Post Syndicated from Sanjay Devireddy original https://aws.amazon.com/blogs/big-data/resolving-concurrent-write-conflicts-for-apache-iceberg-tables-in-amazon-redshift/
In Getting started with Apache Iceberg write support in Amazon Redshift – Part 1, you learned how to create Apache Iceberg tables and write to them with INSERT. In Part 2, you modified data at the row level with DELETE, UPDATE, and MERGE. Both posts assumed your write had the table to itself. In production, that is rarely true: streaming jobs, scheduled pipelines, and one-time transformations frequently write to the same table at the same time. Amazon Redshift now resolves many of these concurrent writes automatically, committing changes that previously failed and were forced to retry. In this post, we explain why concurrent writes to Iceberg tables conflict, how Amazon Redshift resolves the conflicts that don’t actually overlap, how the engine escalates its checks from operations to partitions to individual files, and the throughput improvement it provides.
The challenge of concurrent writes
Apache Iceberg uses optimistic concurrency control (OCC) to keep a table consistent when more than one writer commits at the same time. Each writer prepares its changes against the table’s current version and commits by atomically advancing the table version in the catalog, on the condition that no other writer advanced it first. If another writer commits in the meantime, the condition fails and the entire write is discarded. This strictness maintains snapshot isolation semantics: if the later commit were applied anyway, it would replace the table version without the earlier writer’s changes, silently losing a committed write.
Readers don’t encounter this problem. An Iceberg scan always reads a committed snapshot, so a read is never invalidated by a concurrent write. That leaves write-write conflicts as the only case the engine must resolve, and resolving them correctly is what preserves snapshot isolation semantics for the table.
The problem is the bluntness of this check. The condition is evaluated against the table version, not against the rows or partitions each writer touched. At that grain, its answer is correct in that the version really did change. However, it says nothing about whether the two writes overlapped in the data underneath. Two writers that modified entirely separate partitions, or that independently inserted new data, conflict exactly as hard as two that rewrote the same rows. This happens whenever their query-start-to-commit windows overlap.
Consider a retail analytics platform with a customer_orders Iceberg table. A streaming pipeline might land new orders continuously with hundreds of inserts a minute. A nightly compliance job deletes records older than seven years, and takes about an hour to run. The two writes never touch the same data: the stream only adds recent orders, and the compliance job only removes old ones. Under basic optimistic concurrency, that doesn’t matter. If a single streaming insert commits at any point during that hour, the compliance job loses the race, its hour of work is discarded, and the next attempt re-scans terabytes of data only to re-enter the same race. The table version conflict was real even though the data conflict was not.
The common ways to avoid this are all manual, and each carries a cost. You can serialize your writers so that only one commits at a time, which gives up concurrency entirely. You can split a single logical table into several physical tables so that no two writers ever share one. This trades a clean data model and the ability to query across them for the ability to write in parallel. Or you can wrap every write in an application-side retry loop and absorb the cost of re-running statements that never actually conflicted. In each case, the effort goes toward working around the commit protocol rather than toward your data.
How Amazon Redshift resolves write conflicts
When a commit loses the race, Amazon Redshift now asks a more precise question before giving up: Did the writers that committed ahead of it actually change the same partitions or files or rows it changed? When the answer is no, there’s no reason to discard the work. Instead of aborting, Amazon Redshift rebases the change (similar to git rebase), replaying the already-prepared write onto the latest version of the table and committing that result. Both writes land, with no re-scan, no re-execution, and no retry loop in your application.
In the retail example, the compliance delete previously failed the moment a streaming insert committed inside its execution window. Now Amazon Redshift examines both writes, sees that the inserts only added data files while the delete only removed others, and confirms they never touched the same data. Because the changes are provably independent, Amazon Redshift rebases the delete onto the updated table version and commits it. Both writes succeed, the hour of work is preserved, and downstream consumers see both changes.
This behavior is automatic for eligible writes, with no clustering keys to choose, no repartitioning, and no setting to enable. When two writes genuinely conflict, the behavior is unchanged from today: the conflict surfaces and the later writer fails and must retry.
Two principles govern how the resolution works. The first is that a conflict is a matter of granularity. A failed race isn’t automatically a conflict. It’s a question that can be asked at different resolutions. The engine can ask whether any writer removed data at all or whether they only added it, and if data was removed, whether it came from the same partition, the same file, or the same rows that the current write touched. The finer the granularity examined, the more apparent conflicts turn out to be independent changes that can safely coexist. But finer checks also cost more: taken to the limit, the engine could intersect two change sets row by row, and that is expensive and usually unnecessary. So Amazon Redshift evaluates the least expensive level first and examines a finer level only when it must.
The second principle is that correctness takes precedence over concurrency. Conflict resolution works entirely from table metadata and never re-scans data or re-plans a query. When the engine can’t prove that two writes are independent, it doesn’t guess. It declines to resolve the conflict and the write retries, exactly as it would today. An unnecessary retry costs a small amount of time, whereas an incorrect resolution risks losing data, so the system is deliberately biased toward the safe outcome. Resolution operates under snapshot isolation, the same model Amazon Redshift already uses for Iceberg reads. Engines such as Apache Spark, Amazon EMR, and Amazon Athena honor it through the table’s isolation-level property, so a table shared across engines retains consistent semantics. For tables whose write isolation property is set to serializable, Amazon Redshift preserves the stricter contract and surfaces every conflict rather than resolving it. This is the Iceberg table property write.*.isolation-level. It’s unrelated to the Amazon Redshift database isolation level set with ALTER DATABASE … ISOLATION LEVEL, which governs Amazon Redshift transactions and has no effect on Iceberg commit conflict resolution.
Resolving at the right granularity
When a commit loses the race, the engine escalates through a sequence of checks, from the cheapest to the most precise. Each level is a complete resolution on its own and if a check proves the writes independent, the rebase commits and no finer check runs. The following diagram shows this escalation sequence: an operation-level check first, then partition-level, then file-level. Each level either proves the writes independent or escalates to the next, and a genuine conflict surfaces only after the last.
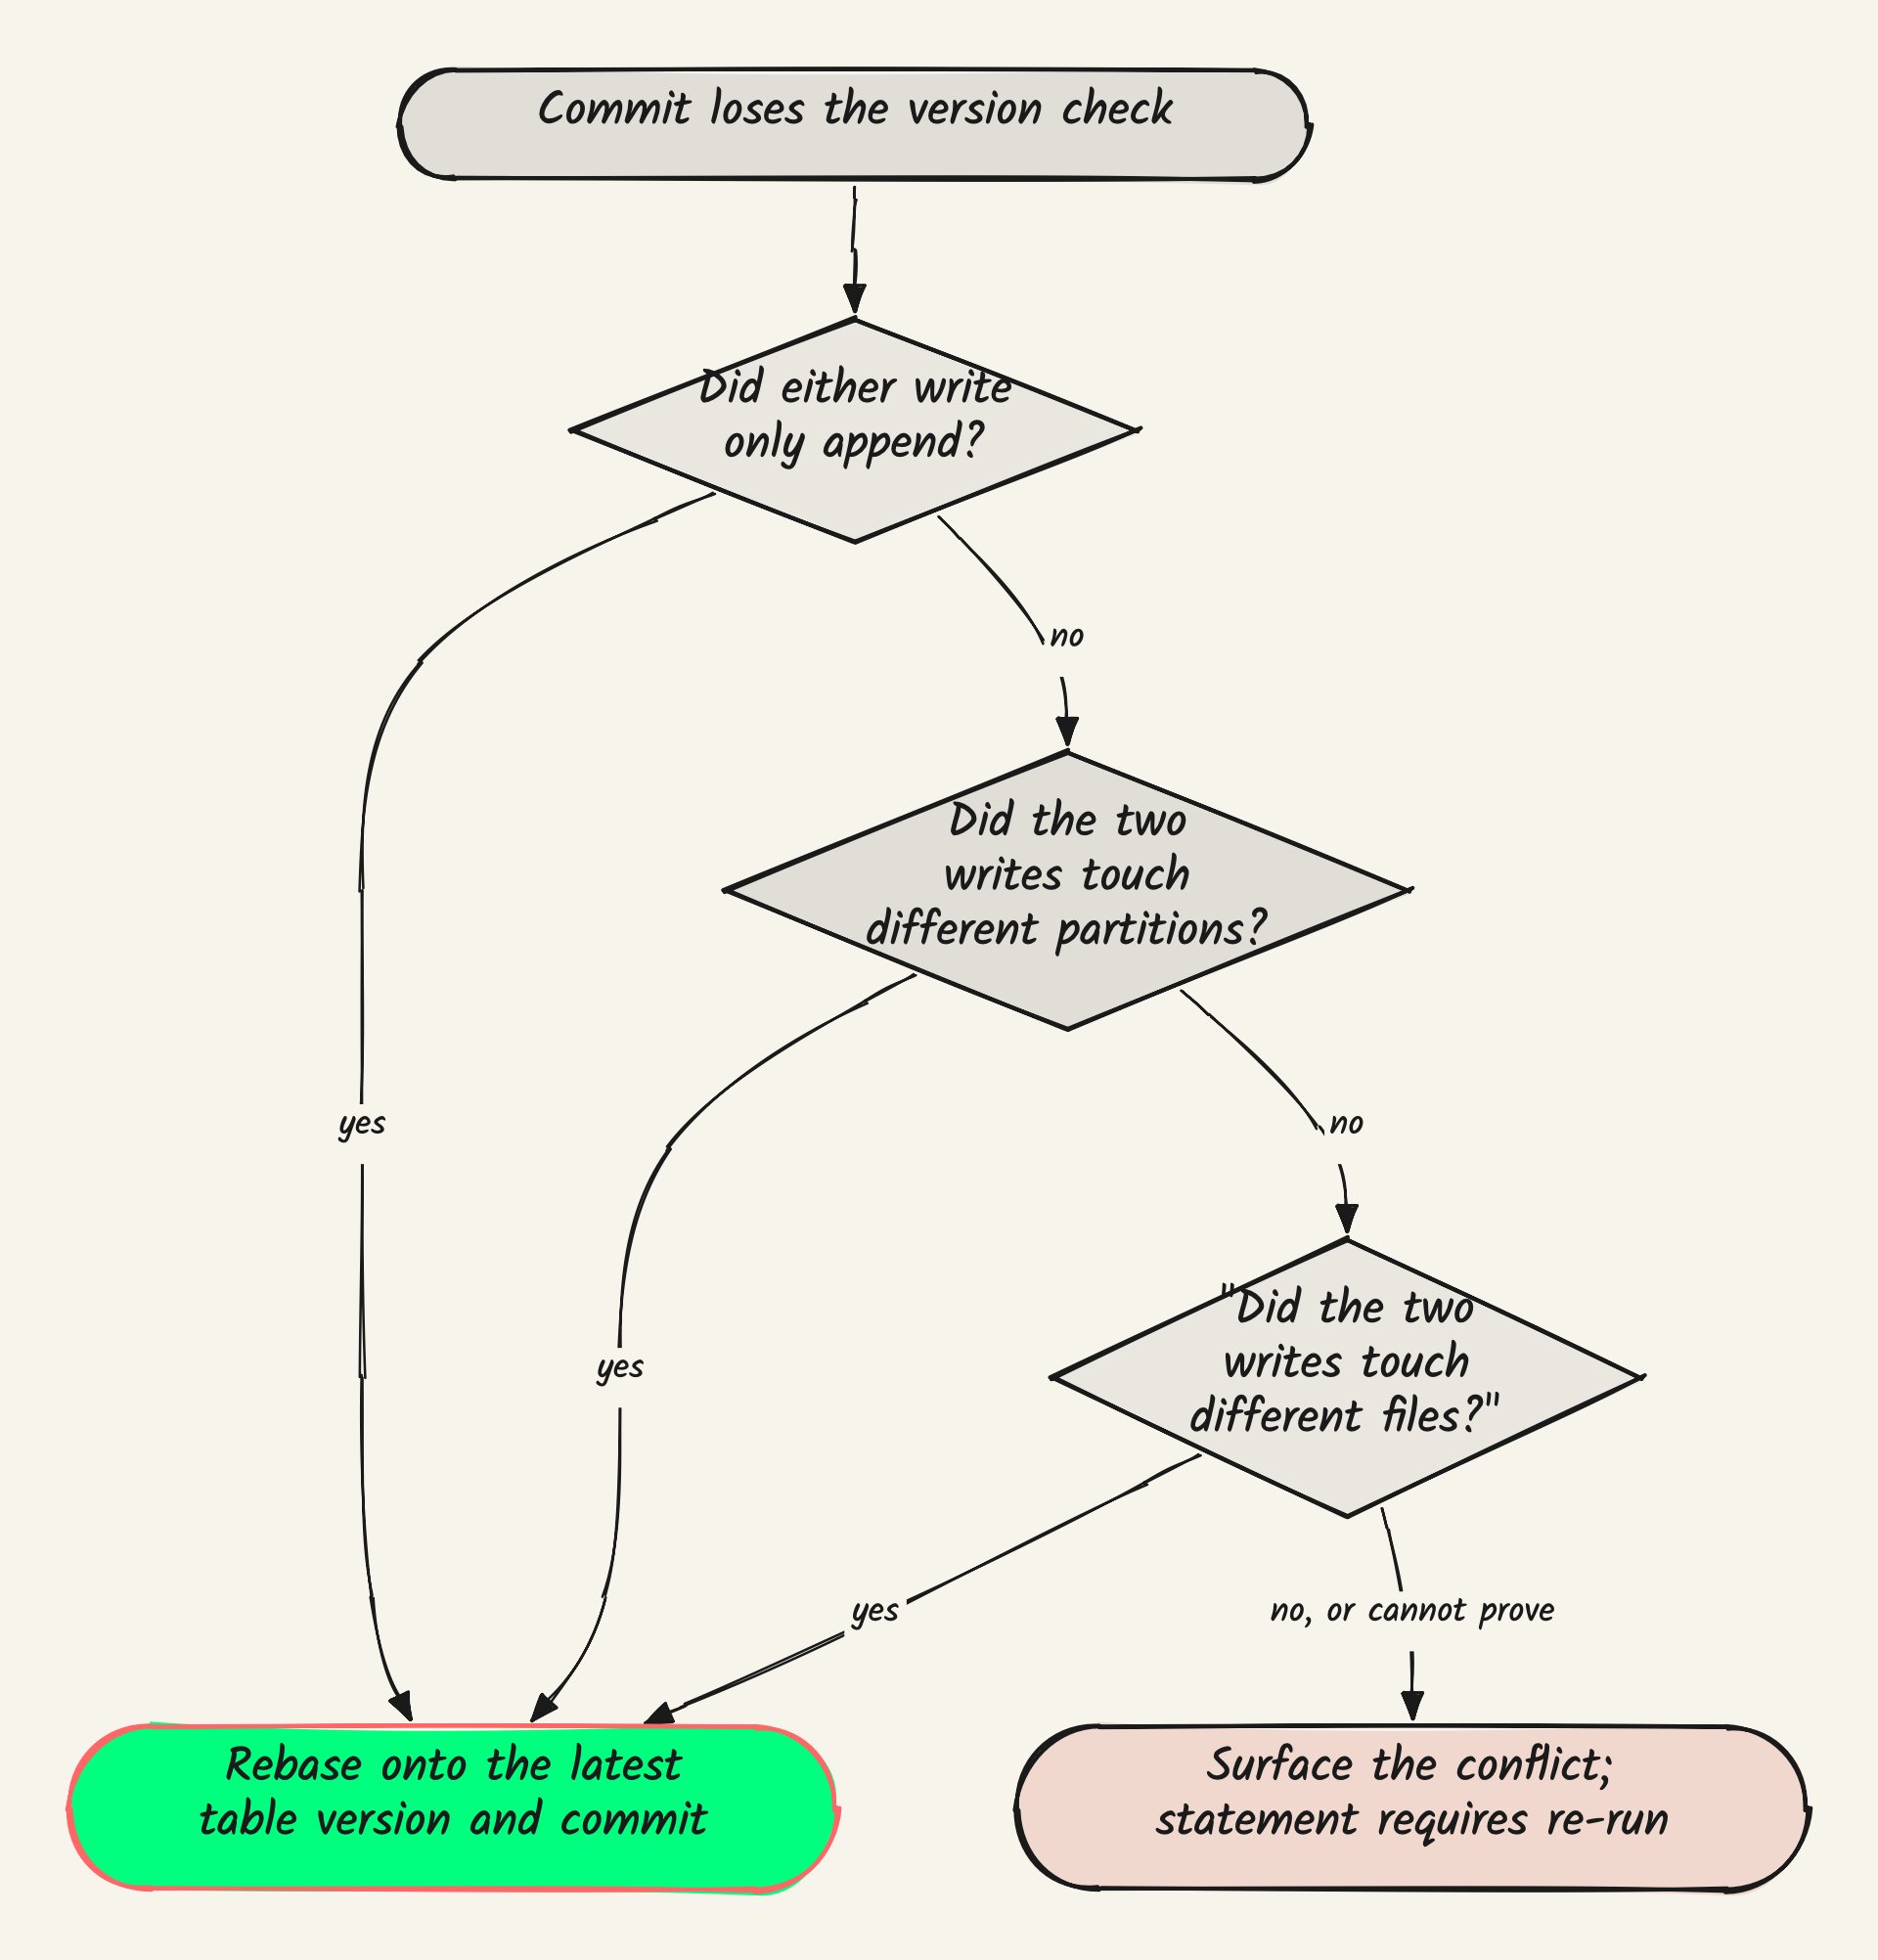
Figure 1: The conflict-resolution escalation from operation-level to partition-level to file-level checks
The first check is by operation. A write that only added data, for example an INSERT consisting of new data landing from a streaming job, can’t have removed anything another writer relied on, so any write can be rebased against it. This single rule resolves every combination in which at least one of the two writes only appended. A DELETE, UPDATE, or MERGE commits cleanly against a stream of concurrent inserts, and an INSERT commits cleanly over any other concurrent change, including a compaction.
Next, when both writes removed data, the engine compares the partitions they each touched. Writes that modified disjoint partitions, for example batch jobs updating different dates or per-Region pipelines maintaining their own slices of one table, are independent by construction and both can commit cleanly.
Finally, when both writes touch the same partition, the engine compares the individual files that each one changed. Two jobs deleting different rows of the same date partition usually land in different files, and when they do, both can commit cleanly. Only when two writes modified the same file does the conflict surface and the statement re-run. The protocol additionally has headroom for one further level: distinguishing changes to different rows within a single file.
The following table summarizes the outcomes by operation pair. Read down for the concurrent write that committed first, and across for your write.
| Your write ↓ / Concurrent write → | INSERT |
DELETE / UPDATE / MERGE |
Compaction | ALTER |
|
| 1 | INSERT |
Resolves | Resolves | Resolves | Re-run required |
| 2 | DELETE / UPDATE / MERGE |
Resolves | Resolves based on partitions or files touched. A same-file change surfaces as a conflict | Resolves based on partitions or files touched. A same-file change surfaces as a conflict | Re-run required |
| 3 | ALTER |
Re-run required | Re-run required | Re-run required | Re-run required |
Performance
To measure the effect, we ran an increasing number of concurrent writers committing to a single Iceberg table over a fixed window. We compared basic optimistic concurrency mode, where a losing commit is aborted and re-runs, against automatic conflict resolution mode being enabled. Every writer issued the same single-statement INSERT, so the only variable across the various runs was contention rather than workload. We scaled 1–16 concurrent writers and recorded, for each configuration, how many commits succeeded and how many were rejected as conflicts.
Setup: one unpartitioned Iceberg table registered in the AWS Glue Data Catalog in the US East (N. Virginia) AWS Region (us-east-1). Each writer is an independent session issuing autocommit INSERT statements in a loop over a 60-second period. We report the commits completed and the attempts rejected as conflicts for each configuration.
The first figure shows write throughput as writers are added, normalized to the single-writer case so the comparison doesn’t depend on instance type or table size.
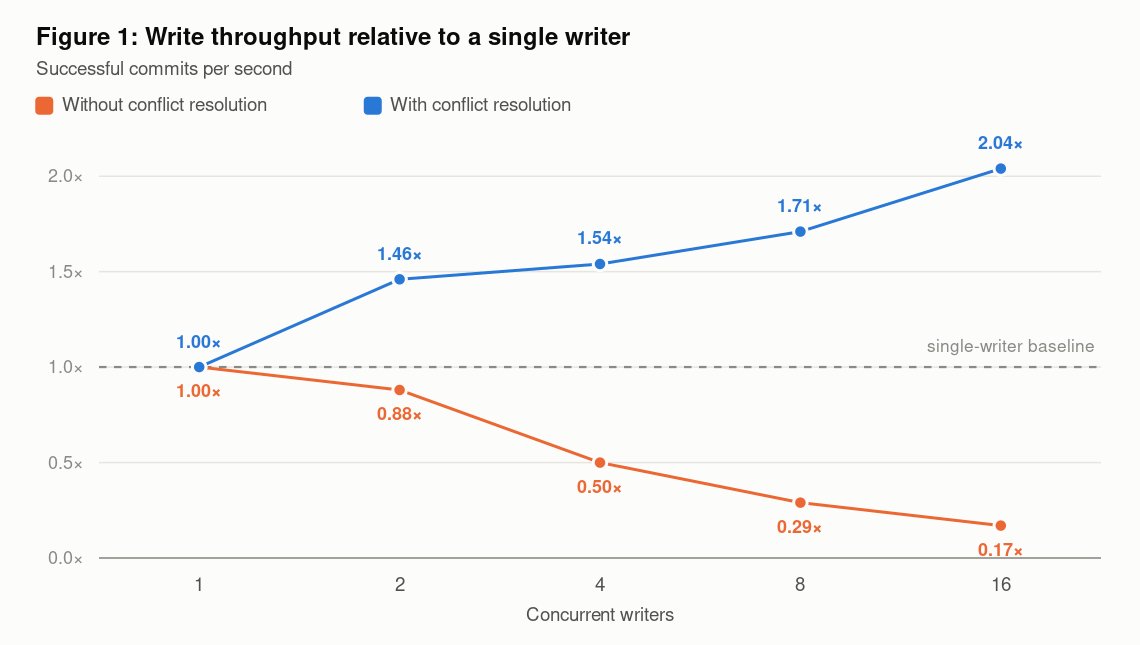
Figure 2: Write throughput as concurrent writers increase, with and without automatic conflict resolution
Under basic optimistic concurrency, adding writers makes writing to the table slower. At 16 writers, throughput falls to 0.17× of a single writer, because nearly every writer’s work is discarded and redone rather than committed. With automatic conflict resolution the same workload scales to roughly 2×, and no commit is rejected in any measured configuration. At 16 concurrent writers, 12× more commits complete in the same window. The second figure shows why.
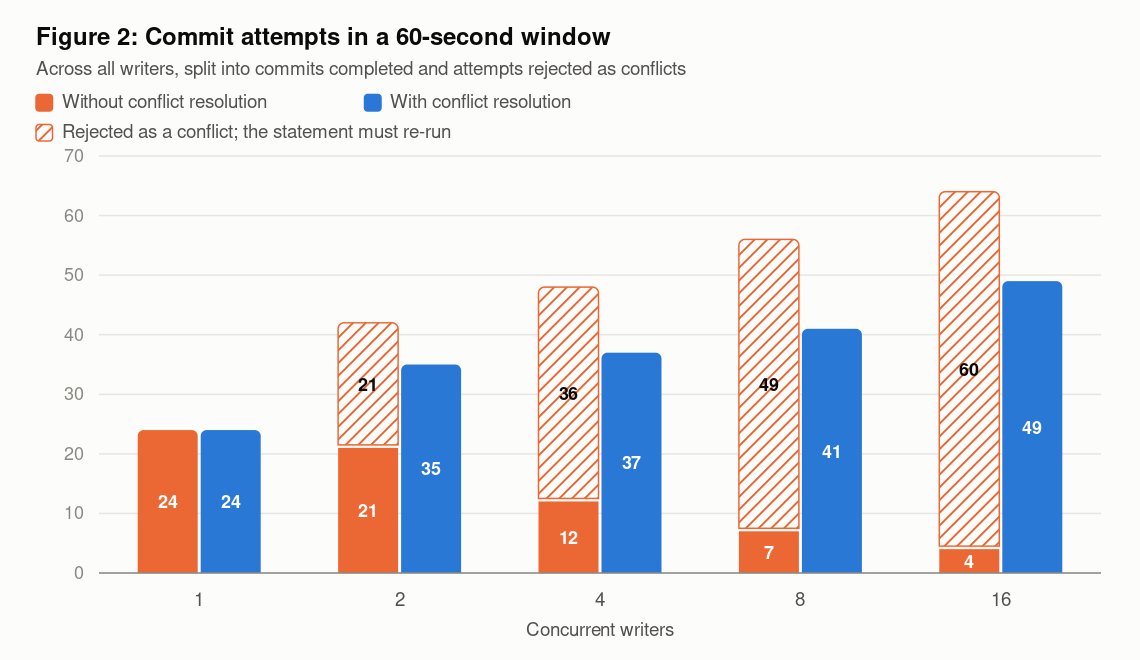
Figure 3: Commit failure rate as concurrent writers increase, with and without automatic conflict resolution
The baseline’s failure rate is almost exactly (N−1)/N, for example 50 percent at two writers, 75 percent at four writers, and 94 percent at 16 writers. This illustrates the table-level check that occurred previously: only one writer wins each commit round and every other writer in flight is rejected. Additional writers translate almost entirely into repeated work rather than progress. With conflict resolution enabled, the same runs record no conflicts at all, because every write in this workload is an append, and an append never removes data another writer relied on.
This benchmark isolates the most basic append case deliberately: a single unpartitioned table and insert-only writers, which is the pattern behind continuous ingestion. Workloads that remove data exercise the partition and file checks described earlier, where the outcome depends on whether the two writes touched the same partition and the same files.
Fleet Results
Before conflict resolution, concurrent-write conflicts were the single largest cause of failed Iceberg writes in Amazon Redshift, accounting for roughly one in five failed Iceberg write queries each week. We rolled out this feature in stages, beginning with the operation-level check that covers concurrent appends. As that stage reached full fleet deployment in early September 2026, conflict errors from concurrent writes dropped to nearly zero, even as Iceberg write volume on the fleet more than doubled. One residual spike shown below came from a workload issuing concurrent UPDATE statements, a conflict class that subsequent partition and file level checks will resolve as they deploy across the fleet.
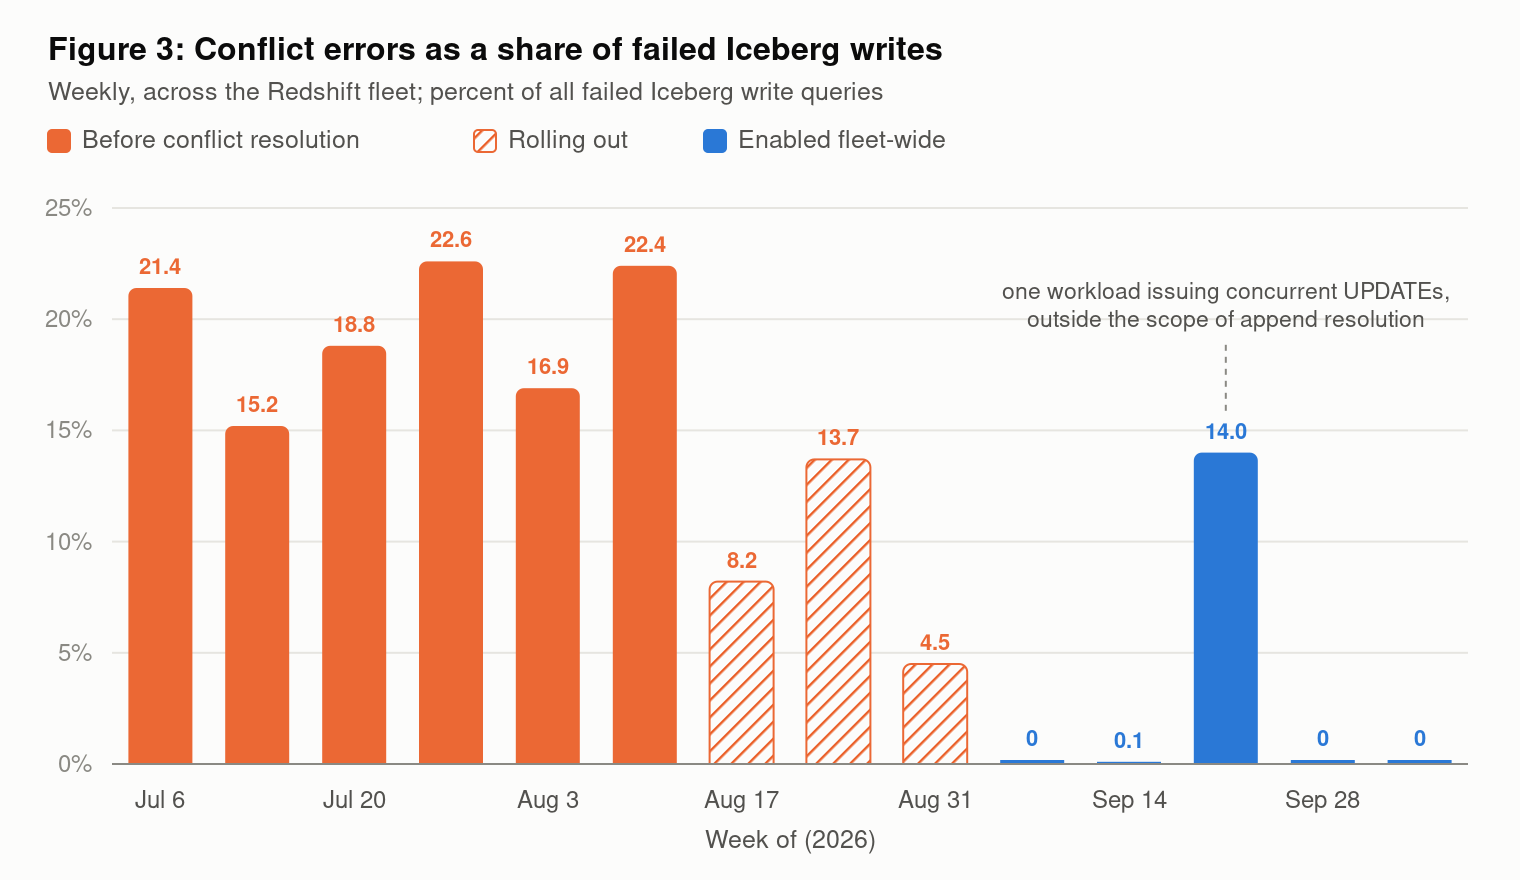
Figure 3: Conflict errors as a share of failed Iceberg writes
Observing conflict resolution
Every Iceberg commit attempt is recorded in the stl_iceberg_commit system table, including the outcome, the number of attempts, the concurrent operations the write rebased over, and the time spent rebasing. To see how often resolution is engaging on an example table:
Conclusion
Concurrent writes are a fact of production data lakes, and until now, they forced you to serialize writers, partition around the problem, or retry. With automatic conflict resolution, Amazon Redshift commits concurrent writes that don’t actually overlap. These include any mix of writes alongside concurrent appends, and row-level writes that changed different partitions or different files of the same table. To get started, write to your Iceberg tables from multiple jobs on patch 203 or later. Non-conflicting commits start to resolve on their own. To learn more about Iceberg write support in Amazon Redshift, see Part 1 and Part 2.