Tag Archives: storage

Introducing Workers KV Instant — powered by Quicksilver

Post Syndicated from Rob Sutter original https://blog.cloudflare.com/workers-kv-instant/

Today, we’re introducing Workers KV Instant, a new mode for Workers KV that pushes your changes globally for instant availability without cold read penalties.

Workers KV has been one of our most popular services on the Developer Platform since launching during Birthday Week in 2018. It’s great for quickly accessing data like static assets and user configuration that is written occasionally but read frequently. We use it ourselves across many Cloudflare products.

We also have another key-value store, Quicksilver, which we’ve blogged about many times since introducing it in 2020. We designed Quicksilver for incredibly fast global replication and low-latency access, and nearly every request to Cloudflare looks up at least one key in Quicksilver. People have asked us for years, but we’ve never made Quicksilver available to our customers.

We’re changing that today with Workers KV Instant. KV Instant mode provides the same API as Workers KV, but powers it using Quicksilver. KV Instant offers 100 times faster p99 reads and immediate updates, with no need to wait for a TTL to expire. It’s not for every type of data, but, for infrequently updated application configuration data — the same thing we use Quicksilver for ourselves — KV Instant shines. 

100x faster reads than Workers KV

KV Instant offers read latency that is over 100 times faster than classic mode, with reads resolving in under two milliseconds even at the 99th percentile of response time (p99), and 95th percentile (p95) times measured in microseconds. Writes are pushed to the edge over 20 times faster, with 99% of all writes replicating in around 250ms.

These high-performance characteristics of KV Instant make it ideal for reading data in the hot path of your applications, especially flags and settings that should be available globally nearly instantly after they’ve been written.

Mode

p99 reads (cached)

p99 reads (all)

median write replication

p95 write replication

p99 write replication 

Instant

N/A

1.62 ms

107 ms (1)

181ms (1)

256 ms (1)

Classic

160 ms

287 ms

< 1 s (2, 3)

< 1 s (2, 3)

4.38 s (2)

Table notes:

  1. Time to replicate to all edge locations (over 300 as of publication)
  2. Time to replicate across all required storage backends
  3. We do not have sub-second fidelity for replication lag in classic mode

KV Instant is powered by Quicksilver v2, a key-value store developed internally by Cloudflare to enable fast global replication and low-latency access on a planet scale.

The same simple API as Workers KV — get(), put() list(), delete()

KV Instant uses the familiar Workers KV API you build with today.

For example, let’s say you’re working on a big product launch, and need to be able to switch what’s on the homepage right at 10:13 AM when the product is introduced at the keynote on stage. You need some key that you can read, that introduces near zero latency, you can read on every request no matter the scale, and updates instantly when you change it.

Most binding operations are compatible with the Workers KV classic equivalents. There are three key differences when working with KV Instant:

  • You must specify KV Instant mode when creating a KV namespace. (pass the ”mode”: “instant” attribute)
  • Metadata is not supported, so getWithMetadata calls always return null and there is no support for passing metadata in put.
  • list operations in KV Instant return all matching keys in a namespace; there is no pagination.

For additional API examples, see the Workers KV docs.

Pricing — reads cost 60% less than classic Workers KV

KV Instant is priced to fit the read-heavy, small data workloads it excels at serving. Because we propagate data to every Cloudflare location, using the same Quicksilver key-value store we’ve spent years learning how to operate at scale on the hot path of every request, we can offer pricing for reads that is 60% less than Workers KV, and much less than other global configuration products.

Conversely, storage and Class A operations are significantly more expensive than Workers KV. If you need to store large amounts of data, or update it frequently, Workers KV continues to be a great fit. Each mode is designed for a very different type of data and access pattern.

KV Instant namespaces are priced in three dimensions: data storage, class A operations, and class B operations.

Class B operations (reads)

Class A operations (put, delete, list)

Storage

Workers KV Instant

$0.20 per million

$0.10 per operation

$100 per MB, per month

Workers KV

$0.50 per million

$5.00 per million

$0.50 per GB, per month

Storage

Storage is billed at $100 per MB, per month. Each key can be up to 300 bytes, and values can be any size that does not cause the namespace to exceed one megabyte in total size. KV Instant namespaces can contain up to 10,000 key value pairs of any type.

Class A operations

Class A operations  (put, delete, and list) are charged at $0.10 per operation. Each key written or deleted counts as one Class A operation. Each list request counts as one Class A operation, regardless of how many keys are returned in the response. A single list operation can return all the key value pairs in a namespace in a single page.

Because writes must pass through a single system of record, KV Instant also restricts write frequency to one write per namespace per second. This is similar to classic Workers KV’s restriction of one write per key per second, and makes it easier for you to reason about update order in your application.

Class B operations

Class B operations (get) are charged at $0.20 per million keys requested, 60% cheaper than Workers KV default mode. When requesting multiple keys in a single get operation, each requested key is billed as one class B operation. For example, the following approaches both incur three class B operations and are equivalent from a billing perspective.

Workers KV Instant is in private beta

KV Instant is launching today in private beta. We’re excited to start working with customers who want to try it, then open it up more widely, and would love to hear from you. You can sign up for the private beta here. Tell us what you’re building!

Amazon S3 Tables now support all Apache Iceberg V3 data types

Post Syndicated from Daniel Abib original https://aws.amazon.com/blogs/aws/amazon-s3-tables-now-support-all-apache-iceberg-v3-data-types/

Amazon S3 Tables now support all data types in the Apache Iceberg V3 specification. You can create V3 tables or upgrade existing V2 tables to take advantage of V3 features like deletion vectors, row lineage, and new data types such as variant, nanosecond timestamps, unknown, geometry, and geography.

Apache Iceberg has become the open standard for managing large analytics datasets. It lets you manage petabyte-scale tables with features like schema evolution, hidden partitioning, and time travel queries, while keeping your data in open Parquet files in data lakes on object storage like Amazon S3. Amazon S3 Tables offer storage purpose-built to keep Iceberg tables performant and cost-effective as they grow, with fully managed features like automatic compaction, maintenance, replication, and Intelligent-Tiering.

Teams running analytics on Apache Iceberg V2 tables often hit the same limits as their data grows. A compliance request to delete 50,000 user records from a 2-billion-row table leaves behind positional delete files that slow queries until compaction runs. Semi-structured events land as JSON strings that every query has to parse. Geospatial coordinates and nanosecond-precision timestamps get encoded as strings or integers. Each workaround adds storage cost, query latency, and pipeline code. With V3, Iceberg solves these challenges by offering native support for semi-structured and geospatial data, faster row-level operations, and built-in row lineage for data governance.

Starting today, Amazon S3 Tables support all V3 data types, including variant, nanosecond timestamps, geometry, geography, and unknown, along with deletion vectors and row lineage. You can create new V3 tables or upgrade existing V2 tables in place, and S3 Tables continue to run compaction and maintenance for you.

Apache Iceberg V3

V3 is the latest version of the Iceberg specification. Among its many improvements, V3 introduces capabilities that address the most common pain points in V2. This includes:

Deletion vectors replace V2’s positional delete files with a compact binary format. That 50,000-row compliance delete now writes a single deletion vector file instead of thousands of small deletes, significantly reducing compaction time and delete file overhead.

Row lineage adds _row_id and _last_updated_sequence_number to each record automatically. Your downstream pipelines can query these fields to find changed rows without scanning the full table.

New data types let you store semi-structured, geospatial, and nanosecond-precision data natively instead of encoding it as strings or integers:

  • Nanosecond timestamp(tz) for nanosecond-precision timestamps
  • Geometry and geography for geospatial data
  • Unknown for columns with no known type

Variant data type stores semi-structured data in columnar format. During writes, the engine shreds variant data into hidden columns and collects statistics. At query time, those statistics enable file pruning that significantly reduces I/O compared to parsing JSON strings.

The following sections walk through how to use these V3 capabilities in practice, with examples that show how to create tables, work with the new data types, and manage data at scale.

Getting started

A retail analytics team tracks user behavior across web and mobile apps. Each event has a different structure: page views include URLs and duration, purchases include items and amounts, and searches include query terms and result counts. With V3’s variant type, you store all event shapes in one table without predefined schemas:

CREATE TABLE my_catalog.namespace.clickstream (
  event_id bigint,
  event_time timestamp,
  user_id string,
  payload variant
)
USING iceberg
TBLPROPERTIES ('format-version' = '3')

Insert events with different payload shapes without worrying about schema evolution:

INSERT INTO my_catalog.namespace.clickstream VALUES
  (1, current_timestamp(), 'user-42',
   PARSE_JSON('{"action": "purchase", "amount": 99.99, "items": ["laptop_stand"]}')),
  (2, current_timestamp(), 'user-17',
   PARSE_JSON('{"action": "page_view", "url": "/products/webcam", "duration_ms": 4200}'));

Now query the variant column directly, without PARSE_JSON at read time. With Amazon EMR Spark, use variant_get:

SELECT
  event_id,
  user_id,
  variant_get(payload, '$.action', 'string') AS action,
  variant_get(payload, '$.amount', 'double') AS amount
FROM my_catalog.namespace.clickstream
WHERE variant_get(payload, '$.action', 'string') = 'purchase'
  AND variant_get(payload, '$.amount', 'double') > 50.00

To enable deletion vectors for write operations, configure merge-on-read mode:

ALTER TABLE my_catalog.namespace.clickstream
SET TBLPROPERTIES (
  'write.delete.mode' = 'merge-on-read',
  'write.update.mode' = 'merge-on-read',
  'write.merge.mode' = 'merge-on-read'
)

Now when you run a compliance delete, V3 writes a small deletion vector instead of rewriting data files:

DELETE FROM my_catalog.namespace.clickstream
WHERE user_id = 'user-42'

S3 Tables compaction handles these deletion vector files automatically on the next maintenance cycle.

Upgrading from V2

AWS provides backwards compatibility for both versions to minimize disruption during migration to V3. Existing V2 readers continue to work on upgraded tables until you’re ready to fully adopt V3 features. For more details, see the S3 Tables Iceberg V3 documentation.

Upgrade an existing table atomically without rewriting data:

ALTER TABLE my_catalog.namespace.existing_table
SET TBLPROPERTIES ('format-version' = '3')

On the next compaction cycle, S3 Tables remove old V2 delete files. New modifications use deletion vectors automatically. Row lineage fields initialize on the first data modification after the upgrade.

This is a one-way operation. The Apache Iceberg specification does not support downgrading from V3 to V2. Verify that all engines accessing the table support V3 before upgrading.

Using row lineage for incremental pipelines

After your table has V3 data, use row lineage to build efficient incremental pipelines:

SELECT *, _row_id, _last_updated_sequence_number
FROM my_catalog.namespace.clickstream
WHERE _last_updated_sequence_number > 42

This returns only rows modified after sequence number 42. Your downstream jobs can checkpoint this value and process only new changes on each run, instead of scanning the full table.

Compatibility across AWS analytics services

AWS offers the broadest native Apache Iceberg support of any major cloud provider, with Iceberg-compatible services at every layer of the data stack: ingestion, storage, catalog, and analytics. You can store and automatically optimize V3 tables in Amazon S3 Tables, write data with Amazon EMR Spark, integrate and manage data with AWS Glue, and run analytics with Amazon Redshift. To learn more about AWS analytics support for V3, see the Apache Iceberg on AWS prescriptive guidance.

Both S3 Tables and AWS Glue Data Catalog support the Iceberg REST Catalog (IRC) API, enabling interoperability across engines regardless of the catalog endpoint.

Things to know

  • S3 Tables compaction fully supports V3 deletion vector files and preserves row lineage metadata.
  • The new V3 data types (variant, nanosecond timestamps, geometry, geography, and unknown) require an engine built on Apache Spark 4.0 or later, such as AWS Glue 6.0 or later, or Amazon EMR release 8.1 or later.
  • You can create V3 tables from the Amazon S3 console, AWS CLI, or any engine that supports the Iceberg REST Catalog API.
  • The new V3 data types are supported only for tables that use the Parquet file format (not ORC or Avro).
  • Columns of type variant, geometry, geography, or nanosecond timestamp can’t be included in a table’s sort order for compaction. Tables containing these columns still compact under the sort and Z-order strategies when the sort order uses columns of other types.

Now available

Amazon S3 Tables support for all Apache Iceberg V3 data types is now available in all AWS Regions where S3 Tables are supported. Apache Iceberg V3 support is available at no additional charge; standard S3 Tables pricing applies.

To get started, visit the Amazon S3 Tables documentation or create a table bucket from the Amazon S3 console. If you want to call APIs, search documentation, find regional availability, and check troubleshooting about this feature, try using the AWS MCP Server and plugins with your preferred AI tool. Send feedback to AWS re:Post or through your usual AWS Support contacts.

– Daniel Abib

Amazon S3 Vectors now supports metadata pre-filtering for higher recall on filtered searches

Post Syndicated from Daniel Abib original https://aws.amazon.com/blogs/aws/amazon-s3-vectors-now-supports-metadata-pre-filtering-for-higher-recall-on-filtered-searches/

Today, we’re announcing metadata pre-filtering for Amazon S3 Vectors, which delivers higher recall on filtered queries by evaluating your metadata filter before the similarity search. You can filter on attributes such as tenant, category, status, or time, and pre-filtering adds prefix matching with $startsWith for paths, URLs, and hierarchical keys. Each vector carries up to 2 KB of filterable metadata, and a single query supports up to 100 filter constraints. There is no additional cost, no re-ingestion, and no change to your queries.

Most applications never search a whole index. They search the part of it that belongs to a particular user, account, or category, and they express that scope as a metadata filter. Semantic search, retrieval-augmented generation (RAG), and agentic applications all need the same thing from a filtered query: a similarity search that covers the vectors matching the filter, and returns the closest of them. With pre-filtering, a filtered query returns more of the relevant matches your index contains, giving you higher recall on filtered searches.

Common use cases

Pre-filtering applies wherever results have to be both relevant and correctly scoped:

  • Legal and professional services: A law firm or e-discovery platform searches documents scoped to a single client, and with $startsWith narrows further by matter number, folder path, or document ID prefix. A single client is a small share of a firm-wide archive, and filters this narrow are where pre-filtering improves recall most.
  • Financial services: An investment research platform searches analyst notes, filings, and call transcripts scoped by issuer, document type, and publication date.
  • Media and entertainment: A streaming service filters by content rating and regional licensing before the semantic search, finding similar titles restricted to G and PG content licensed in one territory.
  • Agentic applications: An agent working within a user’s session filters on fields such as owner, document set, and timestamp so its searches cover the material relevant to the task at hand. Higher recall means more of that material reaches the agent, which improves task reliability

How pre-filtering works

Each vector in an S3 Vectors index can carry application-defined metadata, and a query can filter on those fields.

Every vector index has an index mode. On an index whose index mode is ENHANCED, S3 Vectors resolves your filter first, then searches only the vectors that match. On an index whose index mode is CLASSIC, S3 Vectors performs the vector search and filter evaluation in tandem, validating each candidate vector against your filter as it searches. Existing indexes use CLASSIC until you update them.

Consider a support knowledge base of 8 million tickets, where an agent searches one customer’s history for a recurring error. If that customer accounts for 400 of those tickets, resolving customer_id first means the similarity search runs across all 400 of them, so the agent sees that customer’s prior occurrences. Before the index was updated, the same query drew its candidates from the full 8 million, and the result set contained fewer of that customer’s matching tickets.

On highly selective filters, pre-filtering returns up to 5x more of the matching vectors than the same query returned before on CLASSIC indexes.

Getting started

Before you start, make sure your IAM policy grants permissions for the new actions.

You can get started in three steps. The walkthrough below builds a small product-catalog index and runs a selective filter against it, the same pattern you would use for a multi-tenant RAG store or a document search scoped to one client.

First, create a vector index:

aws s3vectors create-index \
  --index-name product-catalog \
  --vector-bucket-name my-vector-bucket \
  --dimension 1536 \
  --distance-metric cosine

The dimension must match the output size of your embedding model, and distance-metric should match how that model was trained (cosine is common for text embeddings). Second, write vectors with the PutVectors API, attaching up to 2 KB of filterable metadata to each vector:

aws s3vectors put-vectors \
  --index-name product-catalog \
  --vector-bucket-name my-vector-bucket \
  --vectors '[{
    "key": "doc-001",
    "data": {"float32": [0.1, 0.2, 0.3, ...]},
    "metadata": {
      "tenant_id": "t-10428",
      "category": "legal",
      "created_date": "2026-03-15",
      "active": true
    }
  }]'

Each vector carries the attributes your application filters on. In this example, tenant_id scopes results to a single customer, category narrows by document type, created_date records when the document was created, and active is a boolean flag. By default every metadata field is filterable, so you can query on any of them without declaring a schema up front.

Third, run a filtered similarity query with the QueryVectors API. The filter uses a compact JSON syntax where a bare key-value pair is an equality match, and operators such as $and, $or, and $gt combine or refine conditions. Pass --return-metadata so the query returns each vector’s metadata:

aws s3vectors query-vectors \
  --index-name product-catalog \
  --vector-bucket-name my-vector-bucket \
  --query-vector '{"float32": [0.1, 0.2, 0.3, ...]}' \
  --top-k 50 \
  --return-metadata \
  --filter '{"$and": [
    {"tenant_id": "t-10428"},
    {"category": "legal"},
    {"active": true}
  ]}'

The expected result is a single vector, doc-001, the only one matching all three filter conditions (tenant_id, category, and active):

{
  "vectors": [
    {
      "distance": 0.9717477560043335,
      "key": "doc-001",
      "metadata": {
        "tenant_id": "t-10428",
        "category": "legal",
        "created_date": "2026-03-15",
        "active": true
      }
    }
  ],
  "distanceMetric": "cosine"
}

S3 Vectors first narrows the search space to vectors matching all three filter conditions, then returns the 50 most similar vectors from that subset. Because the filter is applied before the search, those results are drawn from across all the vectors that match it.

Prefix matching with $startsWith

Pre-filtering adds a prefix match operator for filtering on paths, URLs, and hierarchical keys. A document store that encodes case and folder structure into a document ID can scope a search to a subtree in one condition:

--filter '{"$startsWith": {"document_id": "matter-4417/exhibits/"}}'

$startsWith joins the existing operators: equality, numeric range, set membership, existence checks, and boolean logic with $and and $or.

Turning on pre-filtering for existing indexes

Call UpdateIndexMode on an existing index to turn on pre-filtering:

aws s3vectors update-index-mode \
  --vector-bucket-name my-vector-bucket \
  --index-name product-catalog \
  --index-mode ENHANCED

Pre-filtering takes effect in place. Your existing vectors are not re-ingested, your queries do not change, and the new filter operators are available immediately.

Here is the difference on the same index and the same query. Before the update, a query scoped to one tenant returns two of the ten results requested:

aws s3vectors query-vectors \
  --vector-bucket-name my-vector-bucket \
  --index-name product-catalog \
  --query-vector '{"float32": [0.1, 0.2, 0.3, ...]}' \
  --top-k 10 \
  --return-metadata \
  --filter '{"tenant_id": "t-10428"}'
{
  "vectors": [
    { "key": "doc-114", "distance": 0.41 },
    { "key": "doc-322", "distance": 0.55 }
  ],
  "distanceMetric": "cosine"
}

After the update, the same query returns a full result set drawn from across that tenant’s documents:

{
  "vectors": [
    { "key": "doc-018", "distance": 0.09 },
    { "key": "doc-207", "distance": 0.13 },
    { "key": "doc-114", "distance": 0.41 },
    ... 7 more
  ],
  "distanceMetric": "cosine"
}

Rolling out across your indexes

Once you have validated pre-filtering on an index, set the default index mode on the vector bucket so that new indexes use ENHANCED without a follow-up call:

aws s3vectors put-vector-bucket-default-index-mode \
  --vector-bucket-name my-vector-bucket \
  --default-index-mode ENHANCED

To bring the rest of your existing indexes across, list them and check the index mode on each one, then call UpdateIndexMode on the ones still using CLASSIC:

aws s3vectors list-indexes \
  --vector-bucket-name my-vector-bucket

aws s3vectors get-index \
  --vector-bucket-name my-vector-bucket \
  --index-name product-catalog

Things to know 

  • Indexes created in vector buckets created on or after September 30, 2026 use index mode ENHANCED. Indexes in buckets that existed before that date use CLASSIC until you set the bucket default, including indexes created in those buckets afterward.
  • A single query supports up to 100 filter constraints, counted per value the filter evaluates. If a query exceeds that, you can usually consolidate the filter, replacing a 300-value $in over legal cases with a single caseId field, for example, or split it into smaller queries, run them in parallel, and merge the results by distance.

Get started today

Metadata pre-filtering is available at no additional cost in all commercial AWS Regions where Amazon S3 Vectors is available, and in the AWS China Regions. You pay standard S3 Vectors pricing for storage, PUT requests, and queries. For full pricing details, visit the Amazon S3 pricing page. For regional availability, visit Amazon S3 Vectors Regions and quotas.

Whether you’re scoping a RAG application to one tenant, scoping an agent’s searches to one user’s documents, or narrowing a catalog search to a licensing window, pre-filtering lets you apply those filters without trading away recall. To learn more and get started, visit the Amazon S3 Vectors documentation. Send feedback to AWS re:Post for S3 or through your usual AWS Support contacts.

— Daniel Abib
Introducing Amazon EBS Volume Clones across AWS accounts

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/introducing-amazon-ebs-volume-clones-across-aws-accounts/

Last year, we introduced Volume Clones of Amazon Elastic Block Store (Amazon EBS), a new capability that lets you create instant point-in-time copies of your EBS volumes within the same Availability Zone.

Today, we are extending Volume Clones with cross-account copy, so you can create copies of your EBS volumes into other AWS accounts and optionally re-encrypt them with an AWS Key Management Service (AWS KMS) key in the target account.

With this new feature, you can use your latest application data to develop, test, and experiment in a secondary environment, while protecting and isolating the information in the production environment. For example, you can create copies of a production environment to refresh test and development environments set up in separate accounts with the desired EBS encryption.

Copy EBS volumes across AWS accounts in action
To create a copy of an EBS volume across accounts, the owners of the volume can first grant the target account access to their volume in AWS Resource Access Manager (RAM), which provides a way to share resources across AWS accounts or within an AWS Organization. Then, from the target account, they can locate the volume they have access to create a copy of it.

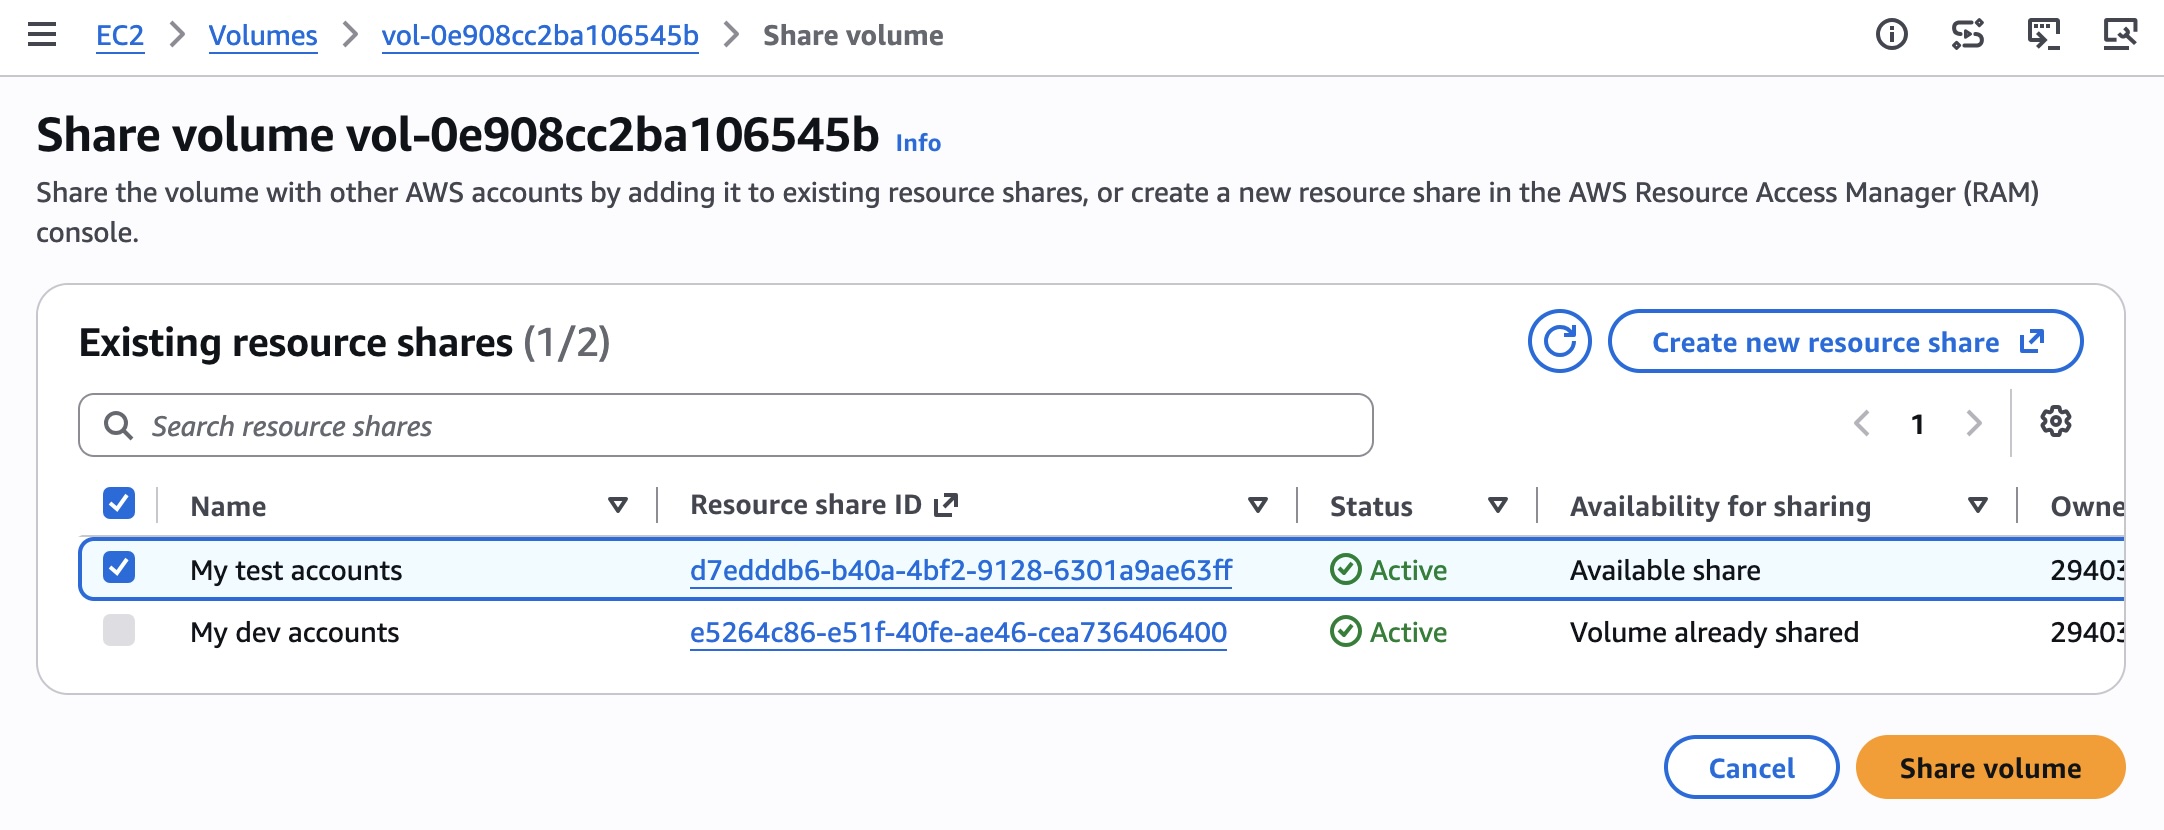
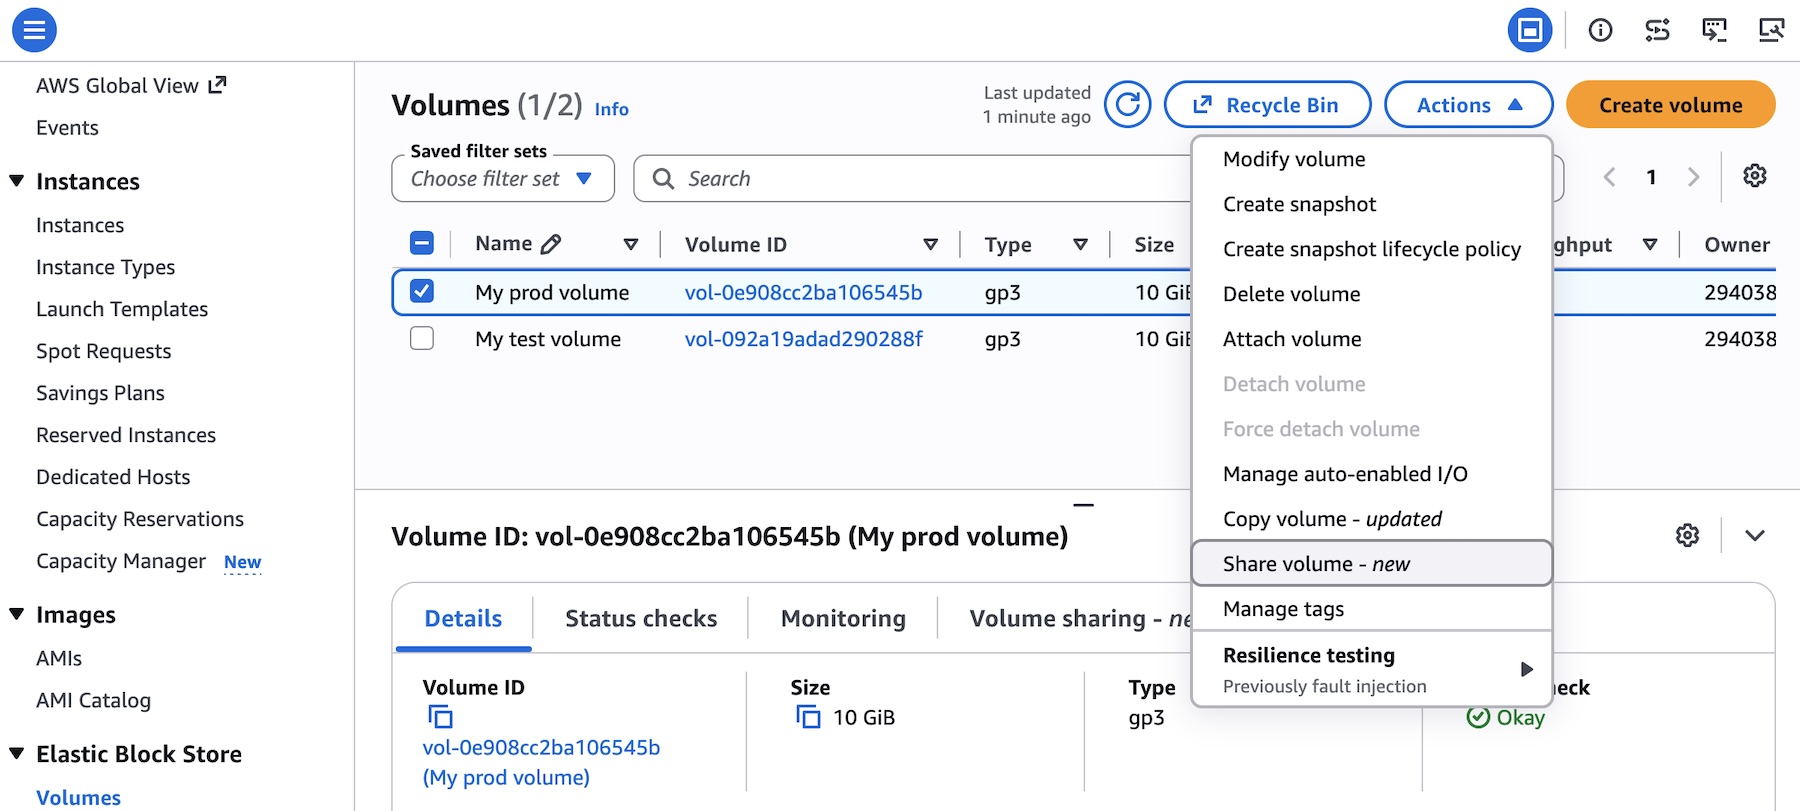
To get started, choose Share volume for the volume you want to share with the target account in the Amazon EBS console.

Share the volume with other AWS accounts by adding it to existing resource shares, or create a new resource share in the AWS RAM console. For more details, refer to the AWS RAM User Guide.

You can now see confirmation that the volume has been shared in the Volume sharing tab of the volume detail page.

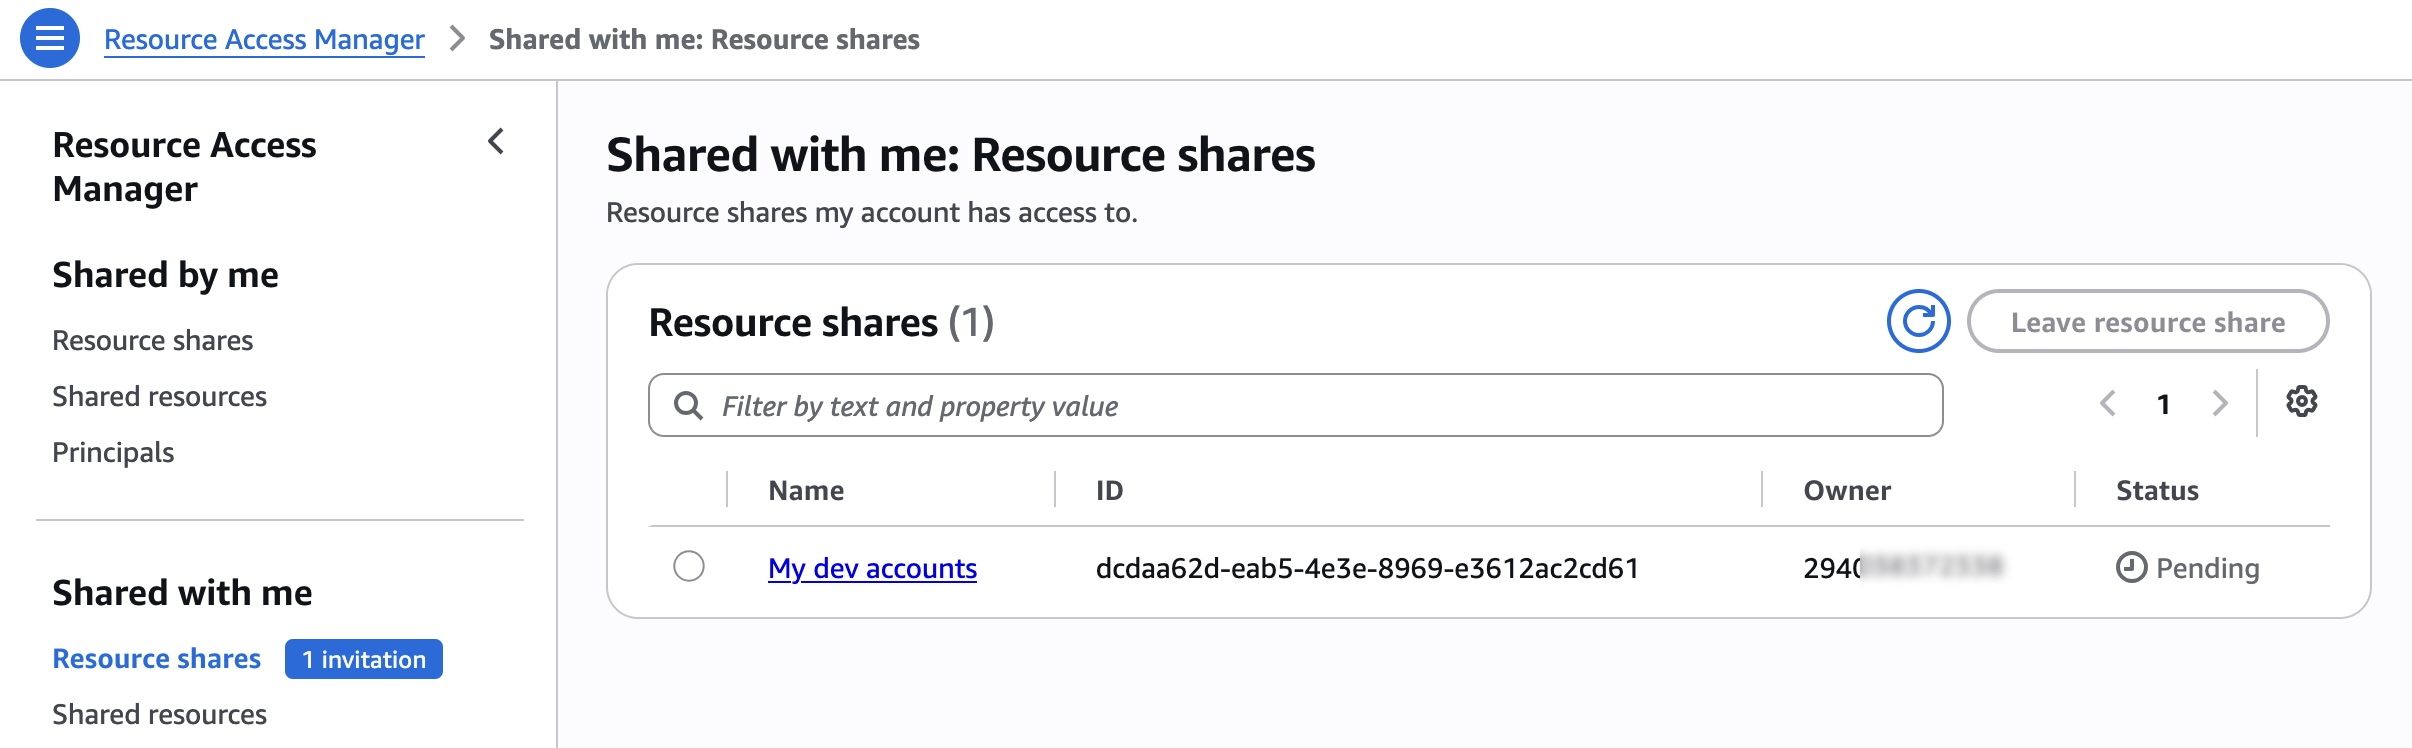
A target account must accept the resource share on the RAM console.

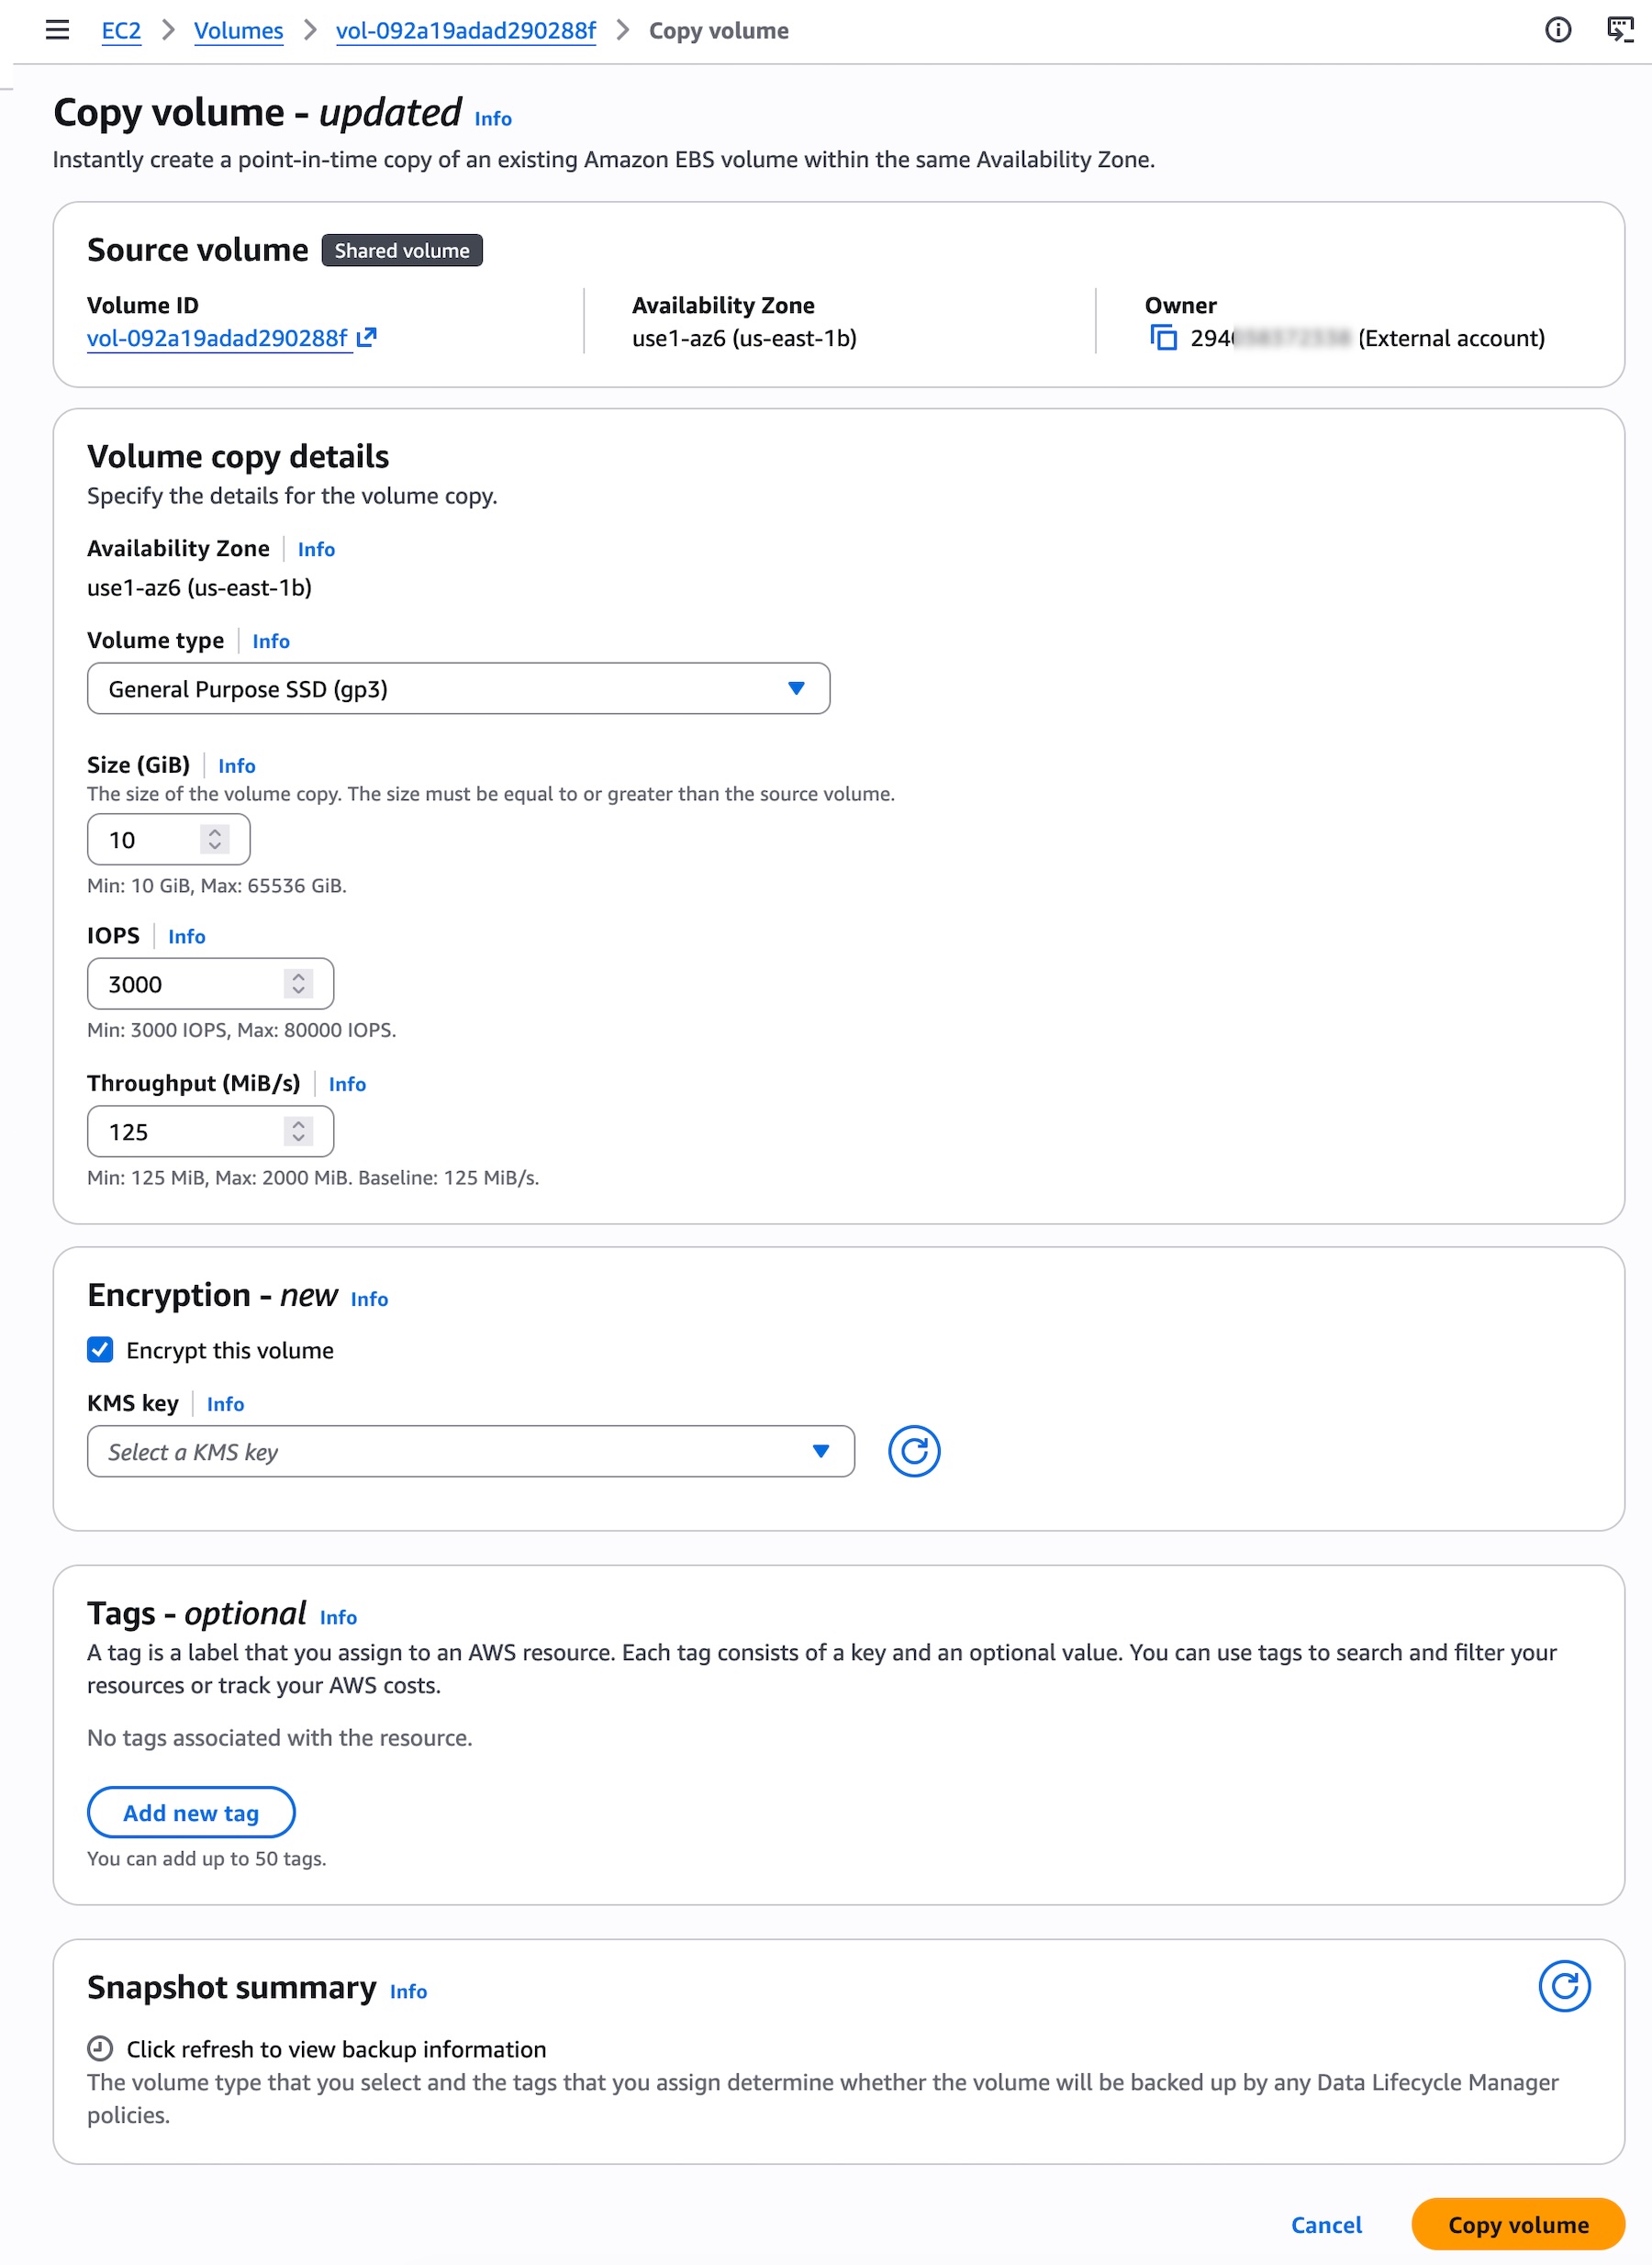
Once they accept the resource share, they can see the volumes in the EBS volume page of the target account. Choose Copy volume for any shared volume.

To share and copy EBS volumes across AWS accounts programmatically, including calling APIs and searching documentation, try the AWS MCP Server and plugins with your preferred AI coding tool. To learn more, visit the Amazon EBS User Guide.

Things to know
Let me share some important technical details that I think you’ll find useful.

  • Encryption: You can share unencrypted volumes and volumes encrypted with a customer managed key (CMK). Volumes encrypted with the default AWS managed key (AMK) cannot be shared. When copying a shared volume encrypted with a CMK, the CMK must also be shared with the target account. You can specify a different CMK to re-encrypt the copy in the target account.
  • Monitoring: You can monitor SharedVolumeCopyInitiated through AWS CloudTrail event in your account. You will also receive events in Amazon EventBridge at the start of the copy operation when the state of the copied volume is initializing, and at the end of the operation when the state of the copied volume changes to completed. You can see the shared volume ID, consuming account ID, and event time.
  • Pricing: Once a copy is initiated, you’ll pay a one-time fee based on your volume size, charged to the account where the copy will reside. There’s no cost for sharing EBS volumes through AWS RAM. The copied volume will incur regular EBS volume charges upon creation.
  • Availability Zone: The volume copy must be created in the same Availability Zone as the source volume. Use Availability Zone IDs (such as use1-az1) to identify the same physical location across accounts.

Now available
Cross-account volume clones for Amazon EBS are available in all AWS Regions that support Amazon EBS Volume Clones. For Regional availability and a future roadmap, visit the AWS Capabilities by Region.

Give this feature a try in the Amazon EC2 console today and send feedback to AWS re:Post for Amazon EBS or through your usual AWS Support contacts.

— Channy

160-bay NVMe SSD 4U Server Shown at FMS 2026 Supermicro ASG-4116S-NU160R

Post Syndicated from Eric Smith original https://www.servethehome.com/160-bay-nvme-ssd-4u-server-shown-at-fms-2026-supermicro-asg-4116s-nu160r/

On the FMS 2026 show floor, we saw a massive 160-bay NVMe storage server (Supermicro ASG-4116S-NU160R) that can deliver crazy storage density

The post 160-bay NVMe SSD 4U Server Shown at FMS 2026 Supermicro ASG-4116S-NU160R appeared first on ServeTheHome.

Spotted at Computex 2026: Micron’s First PCIe Gen6 Data Center SSD, the 9650

Post Syndicated from Ryan Smith original https://www.servethehome.com/spotted-at-computex-2026-microns-first-pcie-gen6-data-center-ssd-the-9650/

Ahead of the launch of PCIe Gen6 CPUs, Micron was at Computex 2026 showing off their first PCIe Gen6 SSD for data centers, the 9650

The post Spotted at Computex 2026: Micron’s First PCIe Gen6 Data Center SSD, the 9650 appeared first on ServeTheHome.

Silicon Motion Shows Off Enterprise SM8008 and SM8388 SSD Controllers at Computex 2026

Post Syndicated from Ryan Smith original https://www.servethehome.com/silicon-motion-shows-off-enterprise-sm8008-sm8388-ssd-controllers-at-computex-2026/

At Computex 2026, Silicon Motion was showcasing its SM8388 and SM8008 SSD controllers for enterprise drives

The post Silicon Motion Shows Off Enterprise SM8008 and SM8388 SSD Controllers at Computex 2026 appeared first on ServeTheHome.

Asustor Showcases Flashstor 12 Pro Gen3 & Flashstor 6 Gen3 All-Flash NASes at Computex 2026

Post Syndicated from Ryan Smith original https://www.servethehome.com/asustor-showcases-flashstor-12-pro-gen3-flashstor-6-gen3-all-flash-nases-at-computex-2026/

For Computex 2026, Asustor had their upcoming third-generation Flashstor NASes on display. With support for either 6 or 12 M.2 SSDs, these all-flash NASes continue to be an interesting offering

The post Asustor Showcases Flashstor 12 Pro Gen3 & Flashstor 6 Gen3 All-Flash NASes at Computex 2026 appeared first on ServeTheHome.