Next in our Ubiquiti switch series is the Ubiquiti UniFi USW-Pro-XG-10-PoE. This is an upgrade to the Ubiquiti UniFi USW-Pro-XG-8-PoE we reviewed, adding more ports, more PoE power budget, and a few more neat features. At the time of this review, this is a $699 device, a notable increase over the $499 lower-end model. As a […]
At Computex 2026 QNAP was showing off a pair of new managed enterprise switches. The QSW-M2130 and 2130P offer 24x 2.5GbE ports and 6x 10GbE ports with both RJ45 and SFP+ backhaul connectivity
Starting today, Cloudflare Internal DNS is generally available. Cloudflare Internal DNS provides authoritative and recursive DNS for private networks on the same global network and control plane customers already use for public DNS, Zero Trust, networking, and application services.
Internal DNS — sometimes also referred to as private DNS — is one of the last pieces of enterprise infrastructure still managed separately from the rest of the network. Many organizations operate one platform for public DNS, another for internal DNS, and use cloud-native DNS services inside each cloud environment with separate security policies layered on top. None of these systems share a common control plane. Split-horizon DNS adds another layer of complexity, often requiring multiple DNS environments to remain synchronized so internal and external users receive different answers for the same hostname. When those systems drift, outages follow.
With Cloudflare Internal DNS, you get a single platform to manage public and private DNS resources, enforcing DNS policies and gaining visibility across your entire DNS stack. For Enterprise customers, this is included with Cloudflare Gateway without any additional charge.
Why customers are adopting Internal DNS
Consolidate DNS operations. Public and private DNS run on one platform, with one API, one audit trail, and one place to set policy. The appliance refresh cycle and the scaling bottlenecks that came with legacy DNS go away.
Simplify split-horizon DNS. Internal and external resolution are defined as separate views over shared zones, managed from a single control plane. There are no parallel systems to keep in sync, so there's no drift to chase down.
Extend Zero Trust to DNS. Resolver policies decide which users and devices resolve against which view, enforced by the same Cloudflare Gateway that already governs the rest of your traffic. Private name resolution stops being the gap in an otherwise Zero Trust architecture.
Modernize legacy infrastructure. Retire hardware appliances, legacy DNS servers, and cloud-locked resolvers. Cloudflare Internal DNS runs on the infrastructure behind 1.1.1.1, with no hardware to rack and no capacity to provision.
What we built
Cloudflare Internal DNS consists of two components: Gateway Resolver and Internal Authoritative DNS. Authoritatively managing zones is a different job from enforcing DNS security and routing policies.
The Gateway Resolver handles recursive resolution and policy evaluation. Launched in 2020 and powered by 1.1.1.1 for public resolution, it comes with a built-in policy engine that can filter DNS queries and redirect queries to different upstream sources — all based on flexible expressions, with comprehensive logging and audits feeding a single pane of glass.
Internal Authoritative DNS serves records for internal zones built on the same authoritative platform Cloudflare has operated for over a decade and that serves more domains than any other provider.
There are three primary objects customers work with:
Internal Zones hold the authoritative records for private resources: environment-specific apps, service endpoints, databases.
DNS Views group zones into the resolution context a given set of users or devices should see. This is what makes split-horizon work without parallel systems.
Resolver Policies sit in Gateway and route matching queries to a specific view.
Zone references let administrators reuse a shared zone across multiple views rather than copying its records into each one. A common zone like intranet.local is defined once and referenced everywhere it's needed, which is the difference between a Don't-Repeat-Yourself configuration and the duplicated, drift-prone setup that split-horizon usually forces.
How a query resolves
A DNS query from a client first hits the Gateway Resolver, where policy is evaluated. From there, one of three things happens. If a resolver policy matches and points at an internal view, the query is routed to Internal Authoritative DNS and answered from the matching view's zones. If policy blocks the query, it is dropped at the resolver. Otherwise, the query follows the public path, with 1.1.1.1 resolving it against the public DNS hierarchy. Views can also fall back to public resolution when a name isn't found internally, so a single resolver can serve both private and public names without the client needing to know which is which.
How a change propagates
Record changes follow a predictable, high-speed path from input to edge.
Every change enters through the same DNS Records API, whether it originates in the dashboard, in Terraform, or in a direct API call. That unified ingress means there is exactly one write path to reason about and audit, regardless of how the change was made. The change is persisted in Cloudflare's core data centers for durability and validated before it propagates.
From there, changes replicate across Cloudflare's global network and affected cached entries are invalidated as the updates arrive, so edited records take effect in seconds rather than waiting on TTL expiry.
Getting started
If you're an Enterprise customer using Cloudflare Gateway, you have access to Internal DNS today. Open the Cloudflare dashboard, navigate to Networking, then Internal DNS.
Setting up Internal DNS typically takes three steps: create a zone, create a view, and define a resolver policy that determines which users and devices should resolve against that view.
Create an internal zone and your first internal record:
Then create a DNS view and link your zone to it:
Finally, create a Gateway resolver policy in the Zero Trust dashboard that routes matching traffic to your view. Create a Gateway location, set your conditions, select Internal DNS View as the resolution method, and choose your view. That's it. Queries matching your policy now resolve against your internal zones.
Terraform support is available, and because Terraform writes through the same DNS Records API as everything else, infrastructure-as-code changes follow the identical ingestion and propagation path. Full documentation and end-to-end configuration examples are available in our developer documentation.
Internal DNS as part of the Connectivity Cloud
Internal DNS works with any Cloudflare connectivity method that routes DNS traffic through the Gateway Resolver, including the Cloudflare One Client (formerly WARP), DNS over HTTPS (DoH), DNS over TLS (DoT), standard DNS on port 53, PAC file deployments, and Cloudflare WAN.
For organizations running Cloudflare WAN, every device on the connected network can resolve internal hostnames through Cloudflare without requiring the Cloudflare One Client on individual devices. The result is a consistent DNS experience across remote users, branch offices, data centers, and cloud environments using a single control plane.
More importantly, Internal DNS is not a standalone DNS service. It extends the same Connectivity Cloud platform that organizations already use to secure users with Zero Trust, connect networks with Cloudflare WAN, accelerate applications, and protect Internet-facing services.
Bringing private DNS onto the same global network as everything else is just the starting point. Tighter integration across DNS, networking, and Zero Trust policy is where this goes next — so resolving an internal hostname, reaching the service behind it, and enforcing who is allowed to access it become decisions made through a single platform, rather than multiple disconnected systems.
Ready to consolidate your DNS? Open the dashboard, head to Networking, then Internal DNS, and create your first zone today. Questions or want to compare notes with other operators? Join the conversation in the Cloudflare Community.
Cloudflare’s core is the centralized data centers that run our control plane, billing, and analytics — distinct from the globally distributed edge that handles user traffic. Core servers are bare metal, and when issues happen during reboot, the consequences can cascade fast.
Their boot sequence is orchestrated by UEFI, the modern firmware standard that initializes hardware and hands off control to the operating system. Small quirks in that handoff can have outsized consequences.
After a routine firmware update, some of our core servers were taking four hours to come back online, rather than just minutes as they did before. What should have been a one-day fleet-wide rollout was stretching into multi-day slogs. New nodes faced the full timeout gauntlet on their very first boot. Maintenance windows ballooned. Engineering teams had to babysit upgrades that should have run unattended.
This issue affected the entire Gen12 fleet — nearly 2,000 units. Every unexpected failure mid-upgrade meant restarting the entire cycle, and new capacity sat idle waiting for the timeout gauntlet to clear.
This is the story of how we tracked the cause to a firmware quirk and an over-eager linear search through every available network boot interface, and how we cut total boot and upgrade time from hours back down to minutes. Along the way, we’ll share what we learned about UEFI internals, vendor-specific quirks, and the automation strategies that ultimately solved the problem.
The network boot interface
A network boot interface allows a server to boot its operating system over the network instead of from local storage. This is critical for centralized, automated, and scalable control over how machines start up, especially across a globally distributed fleet serving different workloads. Since our servers are located in different environments and serve different purposes, they have different requirements for a specific network boot interface. The two primary interfaces are the Preboot Execution Environment (PXE) and Unified Extensible Firmware Interface (UEFI) HTTPS boot.
As part of our reboot process, our servers usually go through PXE for various automation reasons. At Cloudflare, we use the open-source iPXE, an open-source network boot firmware that supports modern protocols like HTTP and HTTPS. This allows computers to boot operating systems directly from web servers, the cloud, or enterprise storage networks with significantly faster speeds and greater reliability.
For organizations, iPXE turns the boot process into a programmable workflow. It offers advanced scripting capabilities that allow IT teams to automate complex deployments, such as provisioning servers based on specific hardware configurations or managing secure, diskless workstations.
Some of our hardware supports HTTPS-based UEFI network boot, which enables the computer’s motherboard firmware to natively download operating system files securely.
The linear search
Our tale begins with that fateful firmware update. Following the update, the first reports came through our internal channels: servers weren’t coming back online. Monitoring dashboards showed machines stuck in a pre-OS state for far longer than expected. Our initial suspicion was a firmware regression: perhaps the update itself had introduced a bug that was hanging the boot process.
To rule that out, we pulled up the serial console on an affected machine and watched a boot cycle in real time. The firmware Power On Self Test (POST) completed normally and hardware initialization looked healthy. But then, instead of quickly reaching the network boot stage and pulling down an OS image, the server sat waiting. And waiting.
The console output told the story: the system was attempting an IPv4 HTTPS network boot, timing out after several minutes, then trying IPv4 iPXE, timing out again, then repeating both — all before finally reaching the IPv6 HTTPS boot interface that would actually succeed.
Every failed network boot attempt burned roughly five minutes waiting for a timeout response. With four attempts stacking up before the correct interface was reached, a single boot cycle wasted around twenty minutes. For a routine reboot, that’s painful. For firmware upgrade automation, which requires multiple sequential reboots, one per component, those twenty-minute penalties compounded into nearly four hours of idle waiting per server.
No searching games: Declare my boot interface
After tracing the boot sequence and isolating the timeout pattern, the root cause became clear: the servers were blindly searching through every available network boot interface, one by one, waiting for each to fail before moving on. The fix was to eliminate the guesswork entirely — declare the correct boot interface upfront so the system never wastes time on interfaces that will never respond.
But putting this into practice was far from straightforward. As we explain next, we hit several obstacles: the order of our boot automation workflow, a setting we were blocked from changing, and differing string formats from our different network interface card vendors.
Our boot automation workflow
Our boot automaton flow is in three broad stages: firmware initialization, pre-boot, and kernel startup. After power on, the UEFI firmware does some hardware and peripheral initialization followed by the PXE pre-boot environment. The pre-boot sets up the network card and executes a small program called bootloader, which kickstarts the kernel. It’s in this PXE stage that various network interfaces are probed for the right one. On first boot, firmware upgrades are included in our boot automation workflow.
And because each firmware upgrade requires a reboot (and its attendant network boot attempt sequence), that’s how we got to the situation where the total boot time took close to four hours.
By restructuring the automation sequence to declare the network boot interface order early on in the pre-boot PXE stage for each hardware/use-case, we were able to cut the total time by about an hour, since the boot process no longer needed to spend 20 minutes probing for each firmware upgrade.
Attempting to declare the network boot interface order introduced two specific constraints:
Legacy Support: Boot ordering is not supported on older UEFI versions
Persistence: Configuration settings are often reset following a UEFI firmware upgrade
To address these edge cases, we implemented a state validation step. The firmware automation now validates the configuration post-change: if it detects that settings have been modified, it re-applies the config and triggers a reboot.
Although the first boot may take slightly longer, this change drastically reduces the time required for all future start-ups from about 20 minutes to less than a minute per subsequent boot.
Setting the boot order disabled by the vendor
The internal data structure of the Network Boot settings is an EFI_IFR_REF3 data structure that was being lazy loaded, meaning the data is not instantiated until it is explicitly accessed via a GUI callback:
While this is standard industry practice to accelerate BIOS boot times, it rendered the “Network Boot Interface” invisible to our programmatic scans. Because the structure hadn’t been “loaded” yet, our automation couldn’t discover the priorities.
We worked with our vendors to enable specific tokens within the fixed “Boot Order Module.” This forces the discovery of the Network Boot Interface during the boot sequence without requiring manual GUI interaction.
The UEFI from our equipment manufacturers had an immutable setting, Force Priority Httpv4 Httpv6 Pxev4 Pxev6, that was preventing us from changing the boot order.
This required a new BIOS version from our vendor and a debug session when setting the boot order.
Different strings from different network interface card vendors
Depending on the network interface card (NIC) vendor, the strings would be different, causing a mismatch when configuring the boot order through iPXE.
In order to work around this issue, we had to implement an additional feature to the CfHIIConfig_App tool, allowing it to set the config without having the full string:
.*HTTP.*IPv4.*P1
The config would then be matched against the accepted config strings and would select the correct boot order. We are currently working with our UEFI vendors to standardize the network interface strings to only make use of the relevant information (e.g. protocol, transfer type, port number, and physical slot index) and drop the product details like the MAC address. The product details, if needed, can be read from the embedded vital product detail information of the network interface card. That way we eliminate both configuration drift and the use of wildcards.
Inability to check the config via iPXE
Since iPXE reads this variable as HEX, it was reading the string output as hex. To check if the network boot setting was modified and to reduce boot time (so we don’t have to print the variables before setting them), we implemented a boolean flag, uefi-same-hex, to indicate whether a configuration changed.
This enabled us to run a single set command instead of first running show to compare, and then set if the configuration was not in the desired state.
This enabled us to run a single set command instead of first running show to compare, and then set if the configuration was not in the desired state.
# construct path to read the update variable
set buffer-var-guid 91468514-75bc-4bb5-8f33-91efff9e9b1f
set var-upd-path efivar/CfHIIVarUpd-${buffer-var-guid}

#Run the config change command
imgexec <signed CF UEFI configuration App> set ${uefi-setting}=${uefi-value}

#Compare the update variable with the expected value if it has changed.
#If it has changed, set the local variable to reboot the system
iseq ${uefi-same-hex} ${${var-upd-path}} || set has-changed ${uefi-diff-hex}
The result: a more dynamic system
By eliminating the guesswork from our network boot sequence, we turned a four-hour ordeal back into a 3-minute process. The result is a system where changes are dynamic and no manual BIOS interactions are needed. A single BIOS firmware image serves all SKUs, configuration updates deploy at scale through our existing release pipeline, and the entire workflow operates from iPXE.
Metric
Before ordering change
After ordering change
Firmware Upgrade Automation
Nearly 4 hours
3 minutes
Subsequent Single Boot
About 20 minutes
Less than a minute
None of this would have been possible without digging deep into UEFI internals, collaborating closely with our OEM vendors to unlock capabilities like programmatic boot order control, and leveraging open-source tools like iPXE to build scalable automation.
With each passing day, Cloudflare’s OpenBMC team continues to learn about, experiment with, and optimize the boot process across our core fleet. If you are managing bare-metal infrastructure and struggling with slow server boot times, we hope this post has given you a practical framework for identifying and eliminating unnecessary delays in your own network boot sequence. For those interested in learning more about iPXE and network boot automation, check it out here!
CUBIC, standardized in RFC 9438, is the default congestion controller in Linux, and as a result governs how most TCP and QUIC connections on the public Internet probe for available bandwidth, back off when they detect loss, and recover afterward. At Cloudflare, our open-source implementation of QUIC,quiche, uses CUBIC as its default congestion controller, meaning this code is in the critical path for a significant share of the traffic we serve.
In this post, we’ll tell the story of a bug in which CUBIC’s congestion window (cwnd) gets permanently pinned at its minimum and never recovers from a congestion collapse event.
The story starts with a Linux kernel change aimed at bringing CUBIC into line with the app-limited exclusion described in RFC 9438 §4.2-12 — a fix to a real problem in TCP that, when ported to our QUIC implementation, surfaced unexpected behaviors in quiche. It has a happy ending: an elegant (near-)one-line fix that broke the cycle.
CUBIC’s logic in a nutshell
Before we dive into the core problem, a quick refresher on CCAs may help to set the stage.
The central knob a CCA turns is the congestion window (cwnd): the sender-side cap on how many bytes can be in flight (sent but not yet acknowledged) at any moment. A larger cwnd lets the sender push more data per round trip; a smaller cwnd throttles it. Every loss-based CCA, CUBIC included, is ultimately a policy for how to grow cwnd when the network looks healthy and how to shrink it when it doesn’t.
In essence, CCAs aim to maximize data transfer by inferring the “available bandwidth” of the network; because no one wants to pay for a 1 Gbps subscription and only use a fraction of it. The family of loss-based algorithms, to which CUBIC belongs, operate on a fundamental premise: (1) if there is no packet loss, increase the sending rate (i.e. increase the bandwidth utilization); (2) if there is loss, loss-based algorithms assume that the network’s capacity has been exceeded, and the sender must back off (i.e. decrease the bandwidth utilization).
This logic is built on several assumptions that have been revisited over the years. However, we’ll save that discussion for another time.
The symptom: a test that fails 61% of the time
Our investigation started with the report of unexpected failures in our ingress proxy integration test pipeline. This erratic behavior appeared in tests where CUBIC was evaluated in a scenario of heavy loss in the early part of the connection.
Recovery after congestion collapse is an uncommon regime, but it is exactly the regime a congestion controller exists to handle. Most congestion control tests exercise the steady-state and growth phases of an algorithm; far fewer probe what happens at minimum cwnd, after the connection has been beaten down. Bugs in this corner of the state space are invisible in throughput dashboards, undetectable by static review, and only surface when you deliberately drive a CCA into it and watch whether it can climb back out — which is exactly what this test did.
The simulated test setup includes the following details:
Quiche HTTP/3 client and server running at locally (localhost)
RTT = 10ms (set up in the configuration)
A 10 MB file download over HTTP/3
Using CUBIC congestion control
With 30% random packet loss injected during the first two seconds
After two seconds, loss stops entirely
The test has a generous 10-second timeout to complete the download, which is expected to be completed in four or five seconds
The expected behavior is straightforward: CUBIC should take some hits during the loss phase, reduce its congestion window, and once loss stops, steadily ramp up and finish the download well within the timeout. Instead, we observed in multiple 100-time runs that around 60% of our tests were not able to complete the download within the generous 10-second timeout.
The anomaly: 999 state transitions with zero loss
We instrumentedquiche’s qlog output with packet loss events and built visualizations to understand what was happening inside the congestion controller:
Connection overview of a failing test. After T=2s, packet loss stops entirely — yet cwnd remains pinned at the minimum floor and the congestion state oscillates between recovery and congestion avoidance every ~14ms.
After the two-second (2000 ms) mark, packet loss stops entirely. However, the number of bytes in flight remains flat, which contradicts the core logic of the CUBIC algorithm: in the absence of loss, apply more gas to increase throttle (more bytes in our world). This raises the question: if the network is no longer dropping packets, why is the congestion window failing to grow?
When we zoom into that region, our analysis shows that CUBIC enters a rapid oscillation, shown in our plot as an extended recovery phase, between congestion avoidance state (the operational regime phase) and recovery state (the packet loss recovery state) — 999 transitions in approximately 6.7 seconds. That’s one transition every ~14ms — suspiciously close to the connection’s RTT (10ms). Throughout this entire period, cwnd is locked at the minimum floor: 2700 bytes, or two full-size packets.
Clearly something in CUBIC’s logic is misinterpreting the state of the connection. The key clue is the oscillation period: ~14ms matches the RTT. Whatever is triggering the recovery/avoidance flip is happening once per round trip, in lockstep with connection’s ACK clock; the self-clocking rhythm in which each round-trip’s ACKs from the client trigger the server’s next send. Because this is a download (server to client), the ACKs in question travel client to server, and CUBIC’s state machine runs on the server side: every time those ACKs land, bytes_in_flight drops to zero and the server sends the next two-packet burst, which is what triggers the bug.
To confirm this behavior was CUBIC-specific, we ran the same test with Reno, another member of the loss-based family but with a different growth rate. The results were conclusive: 100% pass rate, showing Reno recovered cleanly after the loss phase, and revealing that this is a CUBIC-related bug.
Reno recovers cleanly after the loss phase ends at T=2s and completes the download by ~5s
Tracing the root cause
Loss-based algorithms have two pedals, gas and brake, with a difference in how they accelerate. Well, CUBIC comes with some extra features. Here we are going to focus on bytes_in_flight == 0.
TCP CUBIC after idle (Linux, 2017)
To understand the bug, we first need to understand the optimization it came from. In 2017,an issue was found with Linux kernel’s CUBIC implementation. Thecommit message explains:
The epoch is only updated/reset initially and when experiencing losses. The delta “t” of now - epoch_start can be arbitrary large after app idle as well as the bic_target. Consequentially the slope (inverse of ca->cnt) would be really large, and eventually ca->cnt would be lower-bounded in the end to 2 to have delayed-ACK slow-start behavior.
This particularly shows up when slow_start_after_idle is disabled as a dangerous cwnd inflation (1.5 x RTT) after few seconds of idle time.
The epoch is the reference timestamp CUBIC uses to anchor its growth curve: W_cubic(delta_t) is parameterized by delta_t = now - epoch_start, and the epoch is reset whenever CUBIC restarts its growth function — most notably after a loss event reduces cwnd. Between resets, delta_t grows monotonically with wall-clock time.
When an application goes idle (stops sending) for a while and then resumes, the CUBIC growth function W_cubic(delta_t) computes delta_t as now - epoch_start, as illustrated in the figure below. Since the epoch wasn’t updated during idle, delta_t is huge, producing an enormous target window — and CUBIC would immediately try to inflate cwnd to an unreasonable value.
Jana Iyengar’s initial fix was to reset `epoch_start` when the application resumes sending. But Neal Cardwell pointed out the flaw in that approach:
…it would ask the CUBIC algorithm to recalculate the curve so that we again start growing steeply upward from where cwnd is now (as CUBIC does just after a loss). Ideally we’d want the cwnd growth curve to be the same shape, just shifted later in time by the amount of the idle period.
The elegant solution, authored by Eric Dumazet, Yuchung Cheng, and Neal Cardwell, was to shift the epoch forward by the idle duration rather than resetting it. This preserves the shape of the CUBIC growth curve — just sliding it in time so that the algorithm picks up where it left off.
The port to quiche (2020)
When CUBIC was first implemented in quiche, this idle-period adjustment was ported. However, QUIC, which runs in the user space, doesn’t have TCP’s kernel-level CA_EVENT_TX_START callback. Instead, the quiche implementation checks for the idle condition inside on_packet_sent():
// cubic.rs — on_packet_sent() (simplified)
/// Updates the state when a packet is sent.
fn on_packet_sent(&mut self, bytes_in_flight: usize, now: Instant, ...) {
    // If the sending burst is restarting (i.e., bytes_in_flight was zero before this send),
    // adjust the congestion recovery start time to account for the gap in sending.
    if bytes_in_flight == 0 {
        let delta = now - self.last_sent_time;
        self.congestion_recovery_start_time += delta;
    }
    // Record the time of this send event.
    self.last_sent_time = now;
}
Where it breaks: the QUIC difference
The fix ported to quiche included a bug in the original kernel change which was fixed by a followup change to the kernel cubic module about a week later. The commit message for the second fix explains:
tcp_cubic: do not set epoch_start in the future
Tracking idle time in bictcp_cwnd_event() is imprecise, as epoch_start
is normally set at ACK processing time, not at send time.
Doing a proper fix would need to add an additional state variable,
and does not seem worth the trouble, given CUBIC bug has been there
forever before Jana noticed it.
Let’s simply not set epoch_start in the future, otherwise bictcp_update() could overflow and CUBIC would again
grow cwnd too fast.
As mentioned in the commit message, recovery start time is set during ACK processing, and the computation of the adjustment based on sent times can push the recovery start time into the future. This explains the oscillation between recovery and congestion avoidance seen on our test. The trap only consistently triggers when every incoming ACK drives bytes_in_flight all the way to zero — which in practice means cwnd has collapsed to its minimum (two packets) and the application has data ready to send another full window the moment an ACK arrives. Outside this regime, bytes_in_flight == 0 is less likely to hold on every send, so it is less likely to trigger the bug.
Why doesn’t this also happen at connection start? The bug only triggers when the connection exits slow-start and switches over to congestion avoidance. Before exiting slow-start, congestion_recovery_start_time is not set, so the buggy branch in on_packet_sent has no recovery boundary to advance. During slow start CUBIC’s cwnd grows by the same Reno-style ack-based rule shared by all loss-based CCAs — the cubic curve and its sensitivity to congestion_recovery_start_time only enter the picture once the connection is in congestion avoidance, meaning the trap needs three things at once: a real loss event to set the recovery boundary, congestion avoidance to be running, and cwnd collapsed to the two-packet floor.
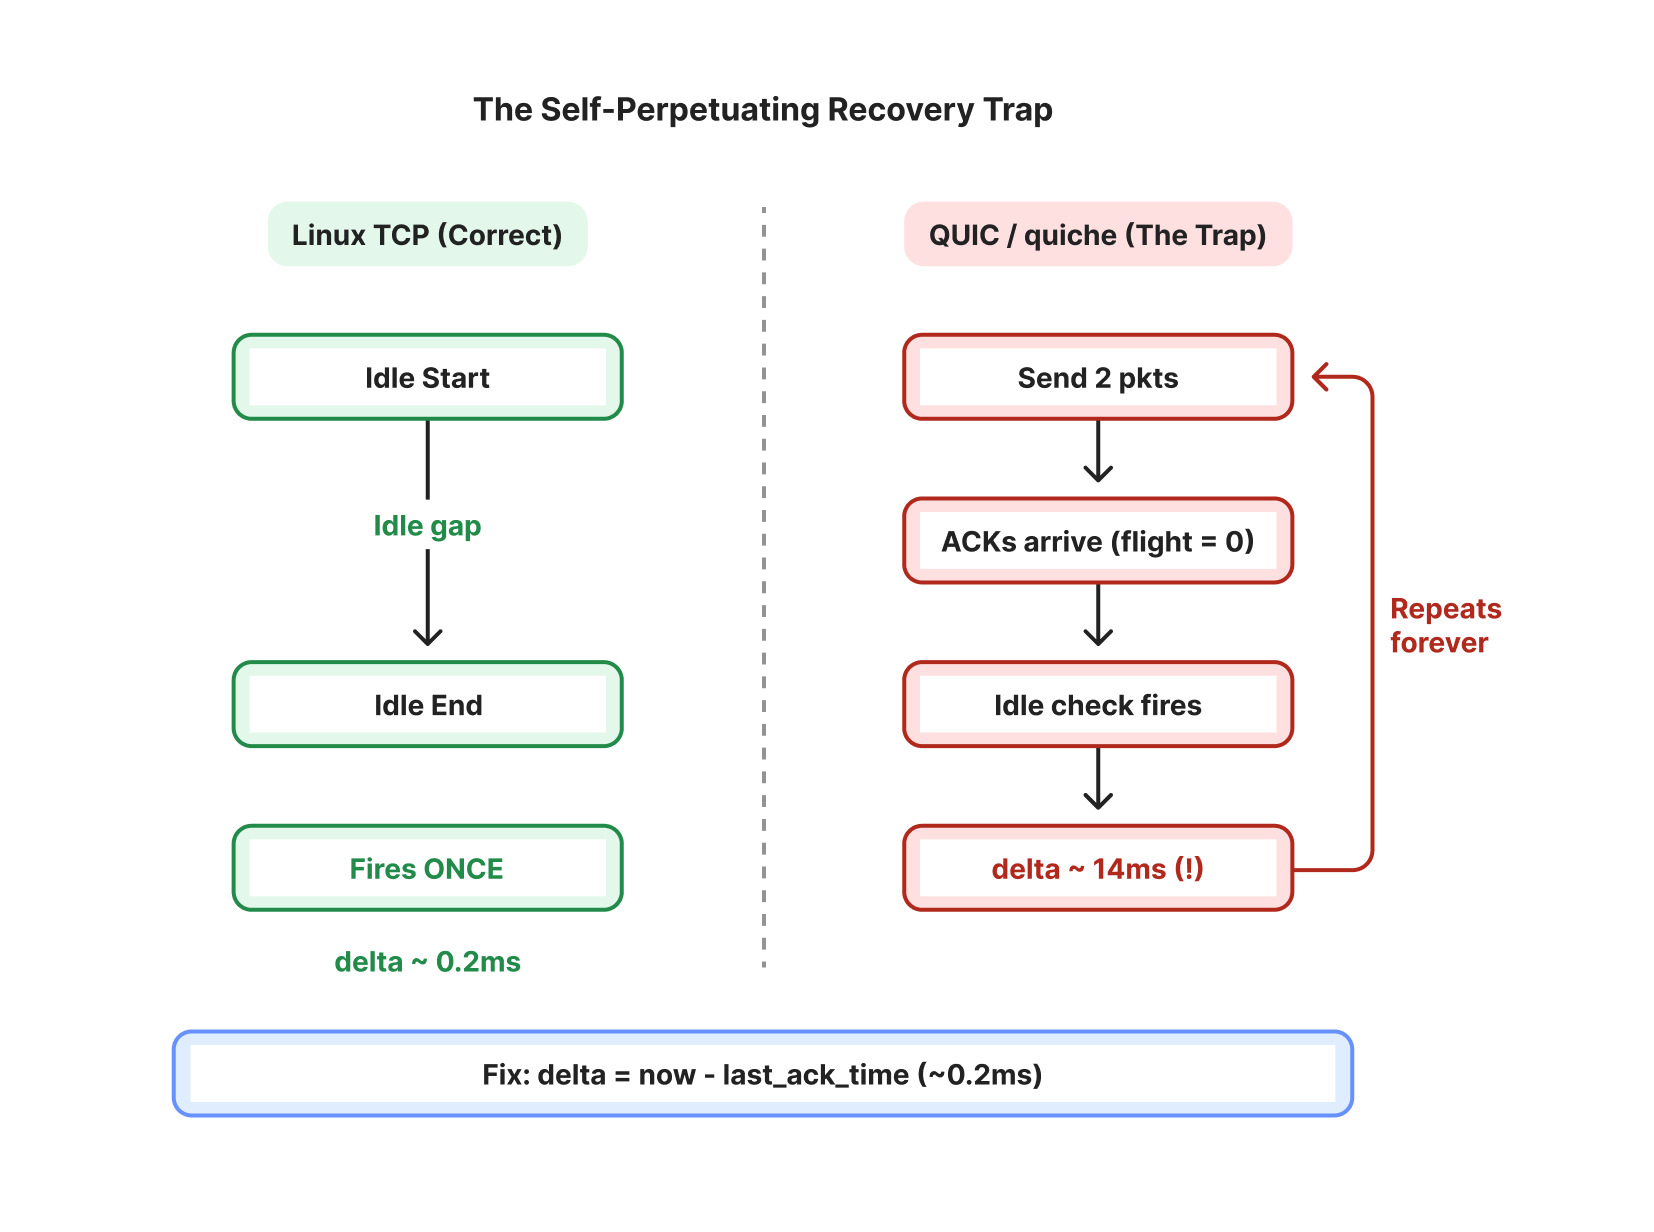
The self-perpetuating recovery trap. At minimum cwnd, every ACK cycle triggers the idle period adjustment with an inflated delta.
At a minimum cwnd (two packets), the dynamics of the connection shift into a “death spiral” where the idle period optimization becomes a self-fulfilling prophecy. This trap operates in a continuous loop:
Send and ACK packets: The sender transmits the entire two-packet window. After one RTT (~14ms), both packets are ACKed, causing bytes_in_flight to drop to zero.
False idle detection: When the next burst is sent, on_packet_sent() sees bytes_in_flight == 0 and assumes the connection was idle, but it was congestion limited.
Inflated delta: The calculation uses now – last_sent_time to determine the idle duration. When the congestion window (cwnd) is at its minimum, last_sent_time is the timestamp of the start of the previous RTT cycle. Therefore, the resulting delta is approximately 14ms (the connection’s RTT + additional rounding errors). This RTT-sized delta is incorrectly applied as the “idle” time. The actual time the connection was idle (the processing gap between the last ACK arriving and the next packet being sent) is effectively 0. By measuring the full RTT instead of the true gap, the delta is inflated significantly, aggressively shifting the recovery start time forward, possibly into the future.
Perceived recovery: Because the recovery start time is now in the future, the in_congestion_recovery() check returns true for every incoming ACK. Processing of the next ACK exits recovery and sets the recovery start to the ACK time which is larger than last_sent_time, making it likely for the congestion controller to push the recovery time into the future when doing the next send.
Stagnation: Since CUBIC skips cwnd growth for any packet perceived to be in a recovery period, the window remains pinned at two packets — ensuring the pipe drains completely on the next ACK and restarting the cycle.
And this loop repeats for thousands of cycles until the accumulation of small deviations — from scheduler jitter and ACK processing variance — lets the <= boundary in in_congestion_recovery() slip behind the next packet’s send time, breaking the cycle.
The fix: measuring idle from the right moment
Fixing the death spiral involves measuring the idle duration from when bytes_in_flight actually transitioned to zero (the last ACK processed) rather than the last packet sent.
The code change
Add last_ack_time timestamp to the CUBIC state.
Update that timestamp when ACKs arrive.
Use it for the idle delta computation:
// cubic.rs — on_packet_sent()
fn on_packet_sent(&mut self, bytes_in_flight: usize, now: Instant, ...) {
    // Check if the connection was idle before this packet was sent.
    if bytes_in_flight == 0 {
        if let Some(recovery_start_time) = r.congestion_recovery_start_time {
            // Measure idle from the most recent activity: either the
            // last ACK (approximating when bif hit 0) or the last data
            // send, whichever is later. Using last_sent_time alone
            // would inflate the delta by a full RTT when cwnd is small
            // and bif transiently hits 0 between ACK and send.
            let idle_start = cmp::max(cubic.last_ack_time, cubic.last_sent_time);

            if let Some(idle_start) = idle_start {
                if idle_start < now {
                    let delta = now - idle_start;
                    r.congestion_recovery_start_time =
                        Some(recovery_start_time + delta);
                }
            }
        }
}
With the delta now reflecting the actual gap since the last ACK, the recovery boundary stops chasing the send time:
Old code: boundary advances one RTT per cycle, always landing on or ahead of the next send.
Fix: boundary barely moves; the next send lands ahead of it and cwnd grows.
For genuinely idle connections, last_ack_time is far in the past and the same expression captures the full idle duration, the original epoch-shift behavior is preserved.
Validation
With the fix applied, the 100% pass rate of our quiche testing suite was restored.
After the fix, cwnd grows along the expected CUBIC curve and the download completes in ~4-5 seconds.
We don’t worry about the losses at the end of the connection — that’s expected because we fully utilized the router’s allocated buffer. In other words, we are fully utilizing the available bandwidth in this test case.
Takeaways
“Idle” is harder to define than it sounds. Normal pipeline delays at small windows can look like idleness to simple checks.
Minimum-cwnd dynamics are a unique corner case. The bug was invisible at high speeds and only triggered after severe loss.
The fix was surprisingly small compared to the complexity of the behavior. After weeks of instrumenting qlogs and analyzing visualizations to find the root cause, the solution required changing just three lines of code. As we noted during the investigation: the effort to find the bug was massive, but the fix itself was basically one line of logic.
The fix described in this post has been contributed to cloudflare/quiche, Cloudflare’s open-source implementation of QUIC and HTTP/3. Our CCA efforts go beyond loss-based algorithms: we also use quiche’s modular congestion control design to experiment with and tune our model-based BBRv3 implementation, now enabled for a growing percentage of our QUIC deployments. Stay tuned for further updates on QUIC congestion control implementation and performance.
If you’re interested in congestion control, transport protocols, or contributing to open-source networking code, check out the quiche repository. We’re always looking for talented engineers who love digging into problems like these, please explore ouropen positions.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.