SemiAnalysis published ClusterMAX 3.0, and storage helps decide whether a neocloud lands in Platinum, Gold, Silver, Bronze, or the new Participation Ribbon tier. Your customers can read that grade before they take your call.
Why it matters: Only 19 of the 77 neoclouds tested in depth earned a Medallion rating, and plenty that held Silver or Gold last round lost it. For most of them, the storage grade doesn’t reflect a decision anyone made. It reflects a default.
Storage decides whether you get rated at all
Storage isn’t something the evaluation gets to eventually. You can’t be rated without it.
Every provider has to supply at least 10TB of high-performance file storage and 10TB of S3-compliant object storage before testing begins.
Then storage is tested twice: once for speed, once for whether that speed holds through 15 minutes of sustained mixed traffic.
Some providers lost nearly 40% of their bandwidth in the second test.
Every neocloud is in one of three states
Size isn’t what matters here. AWS and Azure both had storage problems this round. TensorWave, far smaller than either, had storage SemiAnalysis called exceptional. The difference is whether anyone deliberately decided what storage is for, what it runs on and who owns it.
Not decided yet. You rent GPUs by the hour. Customers bring data in, run a job, and take the results home. Storage is scratch space, and there’s nothing to migrate if you change your mind.
Decided by default. Someone stood something up once, and nobody’s job includes going back to check it. It was fine at the time, and it has stayed “fine at the time” for two years.
Decided deliberately. A person or a contract is responsible for whether it still works, and you pay for that one way or another.
Most neoclouds are in the second state and think they’re in the first. The first state is fine. The second is the one that gets graded.
Why the second state is so common
Decision by default isn’t negligence. If you sell compute by the hour, customers manage their own data, and nobody has to decide what your storage offering is. GPUs are what customers evaluate, so that’s where the attention goes.
But that changes when customers start leaving their data on your platform. Now you have to decide where it lives, who can reach it, what happens when a machine dies and what to charge for it. That decision usually arrives while the business is growing too fast to stop and make it.
What “decision by default” looks like from the outside
SemiAnalysis found four recurring storage failures:
Storage servers not enforcing RBAC correctly on volumes
Storage misconfigured on the overlay network, so customers could reach the underlay
Backend storage sharing a network with no isolation
A BlueField data processing unit (DPU) left in its default host-trusted mode
The DPU case shows the pattern most clearly.
A DPU is a small computer built into the network card. In NVIDIA’s reference design, it handles networking, storage, and security work, including the rules that keep tenants apart. Out of the box, it trusts anyone with root access on the server. That’s fine in NVIDIA’s model, where the server admin is trusted. But in a GPU cloud, the customer often has root. That means the customer can reach the DPU itself, which is the component running the rules that separate them from everyone else on that hardware. Anyone who gets that far is in a position to weaken or turn off the boundary they’re supposed to be sitting behind.
SemiAnalysis found at least one host where that path was open. Nobody chose that setting. It’s how the card ships, and nobody went back to change it.
Read the reviews in tier order and the pattern holds: the further down the tiers, the less anyone has looked at storage.
At the top, the complaints are about ergonomics. CoreWeave’s only storage note was a wish for one-click local GPUDirect Storage, which SemiAnalysis itself called nitpicky.
In the middle, there are configuration gaps. Azure’s default StorageClass couldn’t attach, and a model load from NFS timed out because no parallel filesystem was attached to the Slurm cluster.
At Bronze and below, storage often isn’t set up at all. One Seattle cluster had no shared filesystem to test. Another had no RWX StorageClass, so there was nowhere to put /shared. At a third, NVMe existed but nothing exposed it, and PVCs hung in Pending.
One case sums it up best. A provider’s default StorageClass provisioned and bound, then left the pod stuck in ContainerCreating. Meanwhile, the Lustre tier on the same worker nodes hit 91.7 GB/s aggregate read across 32 clients. The hardware was fast, but anyone who used the default would have concluded the storage didn’t work.
Customers will ask these questions at any size
The tenant-isolation failures SemiAnalysis found hit providers big enough to be testing GB300 racks:
A shared Kubernetes control plane exposing other tenants’ namespaces
A default InfiniBand partition key surfacing 532 hostnames
A Grafana dashboard that separated tenants on screen while the key behind it read every tenant’s logs
That reads like someone else’s problem, but it isn’t. It’s a preview of the diligence review you’ll get the first time a serious customer evaluates you.
The exposed customers in the report included banks, telcos, universities, research institutions, AI labs, and a national intelligence agency. Buyers like these ask:
What isolates my workloads from other tenants: containers, VMs, or dedicated nodes?
Is the control plane shared?
Who can read my volumes, and what enforces that: the storage layer or the interface in front of it?
Is backend storage on its own isolated network?
Can anyone at your company reach my logs and monitoring data without my permission?
Are machines reprovisioned from scratch between customers, or recycled?
It’s important to have answers to these questions before a customer asks, not while they’re waiting.
Three ways out of the second state
Getting out of the second state means picking one of three paths, and committing to it:
Build on Ceph. You get full control over the design and no dependence on anyone else’s release schedule. The cost is a permanent, dedicated headcount line: Ceph specialists aren’t interchangeable with your compute engineers.
Build your own hardware. You design, rack, and run your own storage servers, shaped to your customers’ workloads, and the revenue stays in-house. The cost is procurement, refresh cycles, and capital committed years ahead of demand you can’t forecast.
Partner. Storage works and stays working without anyone on your team owning it, and your engineers stay on compute. What you’re trading is some control: a partner’s pricing, roadmap and deprecation timelines are decisions you’re part of rather than decisions you make alone, and when a customer’s job stalls on storage, they still call you. The right partner expects those questions early and answers them plainly. It’s worth asking before you sign.
All three are legitimate. The option most neoclouds are actually running is none of them.
Decide before the grade, not after
Every provider SemiAnalysis tested had storage. The ones who had decided what it was for, and kept checking that it worked, had an answer when customers asked. The rest had whatever the default gave them, and now that’s published.
If you rent GPUs by the hour today, your customers will eventually stop taking their data home. Decide on your storage before that happens, while there’s less data to migrate, no customers waiting on an answer, and no grade already in front of your prospects.
Read the full reporthere. And visit us to explore how Backblazepartners with neocloudsto ensure more open, AI-ready storage architectures.
Most IT teams feel ready for a ransomware attack. Almost none of them actually are.
A Veeam survey of more than 900 senior IT, security, and risk leaders found that 90% are confident they can recover from a cyber incident. But among organizations hit by ransomware that affected their operations or data, only 28% fully recovered it, and 44% got back less than three-quarters.
That gap is really a gap in backup architecture, not incident response. Ransomware recovery doesn’t come down to how good your plan looks on paper. It comes down to whether your computer backup was built to survive the attack in the first place, and that’s a question worth asking about your endpoints specifically, not just your servers or your cloud storage.
Ransomware goes after your backup before it goes after you
Attackers know backups are the way out, so they target them directly. Veeam’s own data protection research puts the number at 96% of ransomware attacks specifically going after backup repositories, and most of those attempts succeed. A backup that anyone, including an attacker with stolen credentials, can delete or shorten the retention on isn’t a recovery plan. It’s a second target.
This is why deleted file retention and restore permissions matter more than almost anything else here. If a device gets wiped, or an attacker with admin-level access tries to clear out backup history, that data needs to stay recoverable regardless. Backblaze Computer Backup keeps a full year of version history and deleted file retention, and restore and deletion permissions sit with IT centrally, not open at the device level for anyone to touch.
Plenty of legacy endpoint backup tools technically support long retention windows too. The gap can show up at restore time, with heavier clients and more complicated restores. A feature on a spec sheet and a restore that works under pressure are two different things.
If you don’t know who can delete backup history or shorten retention on your current setup, find that out now. Not during an incident.
How far back does your version history actually go?
Ransomware doesn’t always announce itself right away. Some strains sit quietly on a network for weeks, copying and encrypting slowly, before anyone notices. By the time you catch it, your “recent” backup might already be infected.
This is where version history does the real work. If your backup only keeps a few days of history, and the infection has been running for two weeks, you don’t have a clean version to restore to. You have a slightly newer copy of the same problem. This is a common gap with the cloud sync tools plenty of businesses lean on instead of real backup: sync tools keep limited version history that varies by plan, which is fine for undoing an accidental edit and not much else.
One IT director put it plainly when comparing what he had before to what he has now: a full year of version history against a prior vendor’s three-day maximum. His point was simple. The extra retention is what actually lets you go back far enough to find a version worth restoring.
Short retention windows often get sold as a way to keep storage costs down. In practice, they’re one of the more common reasons recovery fails. You don’t find out your version history was too short until you need a version that isn’t there anymore.
Why legal hold has to be part of this conversation
A ransomware incident often triggers more than a technical response. Insurance claims, regulatory questions, sometimes litigation. All of that requires you to preserve data exactly as it was, separate from your normal backup retention rules.
That’s what legal hold is for (available with Computer Backup with Enterprise Controls). It preserves a device’s backed up data beyond your standard retention window. It’s a different function from version history. Version history lets you go back in time. Legal hold freezes a specific point and keeps it there.
The mistake we see most often: IT and legal never talked about this until the middle of an actual incident. By then, you’re improvising a process that should’ve been decided in advance. Decide in advance when a hold would be triggered, and who in IT and legal makes that call.
Endpoints are where recovery actually happens
Company-wide backup policy is one thing. Restoring 40, 100, or 300 individual laptops without your entire IT team dropping everything else is a different problem.
This is where a lot of recovery plans fall apart. They’re written at the policy level and never tested at the device level, and a heavier, more complex client makes that worse under pressure. A few things worth knowing before you’re in the middle of it:
Can you restore a single file without pulling down an entire device image?
Can you restore an entire device to a new machine if the original is unusable?
Who has permission to approve and run a restore, and is that list accurate right now?
For a mass-restore situation across dozens of devices, does your vendor offer any option beyond restoring one machine at a time, like a physical drive shipped with the data preloaded?
These aren’t edge cases. They’re the actual mechanics of recovery, and they’re worth walking through before an attack, not during one.
What recovery looks like at different scales
Here’s roughly what recovery timelines look like in practice, depending on scope:
A single file or folder: depends on whether your version history goes back far enough to find a clean copy.
A single device: depends on the size of the data, your bandwidth, and whether restore access is already sorted out.
A full fleet, dozens to hundreds of devices: this is where things slow down. Restoring machine by machine can take days. Some vendors, including Backblaze, can ship a physical drive preloaded with your data to cut that down significantly.
Only 9% of IT teams describe restoring from backup as “very easy,” according to Backblaze’s State of the Backup Report. Most people find out how hard restoring actually is right when they need it to work.
If you don’t know how you’d handle each of these, that’s worth working out before an incident.
How to pressure test your recovery plan
Everything above is a checklist. Here’s the part that separates a real recovery plan from a hopeful one: walk through a restore on paper, from start to finish, for one real laptop.
Name the device, the person who approves the restore, the person who runs it, and where the data goes. Write down each step and where it could stall.
A vendor’s feature list can tell you whether version history, deleted file retention, legal hold, and endpoint-level restore are technically available. It can’t tell you whether your team knows how to use them under pressure. Walking through the steps, and testing with your vendor’s team in a proof of concept, is how you find the gaps.
Where this leaves your computer backup strategy
Paying a ransom was never a guaranteed fix, and the odds haven’t gotten better. What has changed is how much control you actually have over the outcome, and that control lives almost entirely in your backup architecture, not your incident response plan.
This is also where a lot of endpoint backup tools quietly stop being enough. Some keep only a short version history, like many sync tools. Others price by storage, so a ransomware-driven spike in data or a slow migration off a legacy tool turns into an unplanned bill on top of an already bad week. And a fair number were built for Windows first and adapted for Mac later, which shows up as friction the moment you’re deploying or restoring across a Mac-heavy fleet.
Backblaze Computer Backup with Enterprise Control is built around the specific gaps this post walks through: a full year of version history and deleted file retention, Legal Hold to preserve data beyond standard retention, and restores managed by IT from the admin console. It’s native to Mac and Windows and deploys through Jamf, Iru (formerly Kandji), and Addigy. Pricing is flat per device with no per-GB surprises. None of it replaces good security practices. But it goes a long way toward deciding whether ransomware turns into a bad week or a bad year.
If you haven’t walked through your restore process recently, start there. Pick one machine and map it out this week.
Running a storage cloud means serving as both builder and building inspector. You choose the materials, put them to work at scale, and return quarter after quarter to see how the structure is holding up. After 13+ years of publishing Drive Stats, we know the materials in this particular house pretty well. So, when our preferred home improvement store introduces a new and improved brick (so to speak) we want to understand how it fits into the build.
That question is becoming more relevant as higher-capacity drives become more (dare we say) load bearing. We’ve already been tracking the performance of drives at 20TB and above as a group; later in this installment of Drive Stats, we’ll talk about some of the differences between our current building blocks (CMR HDDs) and the new bricks. But first, to take this extended pun to its inevitable conclusion, the inspection (a.k.a. The Stats).
This Q2 2026 Drive Stats report begins with the latest walkthrough: the quarter’s annualized failure rates, the models that stood out, and the lifetime record of the fleet. Then, we’ll look at some of the emerging technologies that could shape the next phase of construction.
Sign up for the Drive Stats webinar
Ready to dive deeper into the data? Tune in Thursday, October 8 at 12 p.m. PT, as Sr. Market Intelligence Manager, Stephanie Doyle, and Director, Product Marketing, David Johnson review the trends.
Drive Stats: The digest version
Q2 2026 Hard drive failure rates
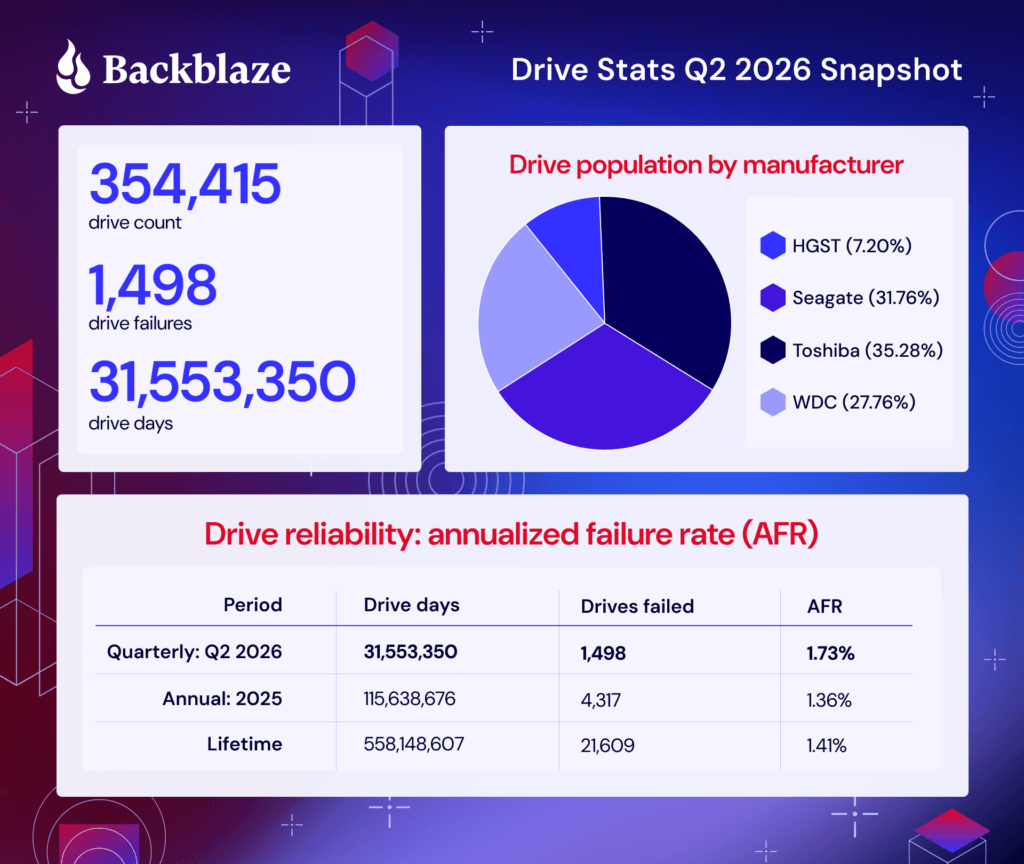
Throughout Q2 2026, Backblaze monitored 359,101 drives used to store data. For our evaluation, we removed from consideration 3,881 boot drives and 705 hard drives, as they did not meet the criteria to be included. We’ll discuss the criteria we used in the next section of this report. Removing these drives leaves us with 354,415 hard drives to analyze. The table below shows the annualized failure rates for Q1 2026 for this collection of drives.
Backblaze Hard Drive Failure Rates for Q2 2026
Reporting period April 1, 2026–June 30, 2026 inclusive Drive models with drive count > 100 and drive days > 10,000 as of June 30, 2026 in Q2 2026.
MFG
Model
Size (TB)
Drive Count
Avg. Age (Months)
Drive Days
Failures
AFR (%)
HGST
HUH721212ALE600
12
2,599
78.4
236,107
7
1.08
HGST
HUH721212ALE604
12
13,196
59.4
1,190,182
109
3.34
HGST
HUH721212ALN604
12
9,694
83.8
861,297
180
7.63
Seagate
ST8000DM002
8
6,903
114.8
563,210
38
2.46
Seagate
ST8000NM000A
8
239
40.4
21,499
0
0
Seagate
ST8000NM0055
8
13,112
104.7
1,177,541
111
3.44
Seagate
ST10000NM0086
10
965
101.7
86,092
22
9.33
Seagate
ST12000NM0007
12
972
78.8
87,496
10
4.17
Seagate
ST12000NM0008
12
18,521
73.7
1,671,057
145
3.17
Seagate
ST12000NM000J
12
1,079
22
97,746
0
0
Seagate
ST12000NM001G
12
13,177
63.7
1,193,856
44
1.35
Seagate
ST14000NM000J
14
497
17
43,349
0
0
Seagate
ST14000NM001G
14
10,498
63.2
949,396
39
1.5
Seagate
ST14000NM0138
14
1,235
65.5
110,410
25
8.26
Seagate
ST16000NM000J
16
171
15.4
14,221
1
2.57
Seagate
ST16000NM001G
16
35,100
43.7
3,162,117
56
0.65
Seagate
ST16000NM002J
16
467
41.7
42,086
4
3.47
Seagate
ST24000NM002H
24
9,631
12.2
861,587
78
3.3
Toshiba
MG07ACA14TA
14
37,171
67.1
3,368,924
179
1.94
Toshiba
MG07ACA14TEY
14
989
42.8
89,164
6
2.46
Toshiba
MG08ACA16TA
16
39,932
33.7
3,614,263
100
1.01
Toshiba
MG08ACA16TE
16
6,306
51.4
568,379
16
1.03
Toshiba
MG08ACA16TEY
16
4,857
53.5
439,243
44
3.66
Toshiba
MG09ACA16TE
16
905
6.2
68,429
2
1.07
Toshiba
MG10ACA20TE
20
25,270
12.1
2,117,524
64
1.1
Toshiba
MG11ACA24TE
24
9,620
5.8
824,903
13
0.58
WDC
WUH721414ALE6L4
14
8,635
64.2
783,318
23
1.07
WDC
WUH721816ALE6L0
16
2,970
53.3
268,875
30
4.07
WDC
WUH721816ALE6L4
16
26,827
37.5
2,432,374
77
1.16
WDC
WUH722222ALE6L4
22
45,665
19.1
4,146,339
63
0.55
WDC
WUH722626ALE6L4
26
7,212
3.4
462,366
12
0.95
Totals
354,415
31,553,350
1,498
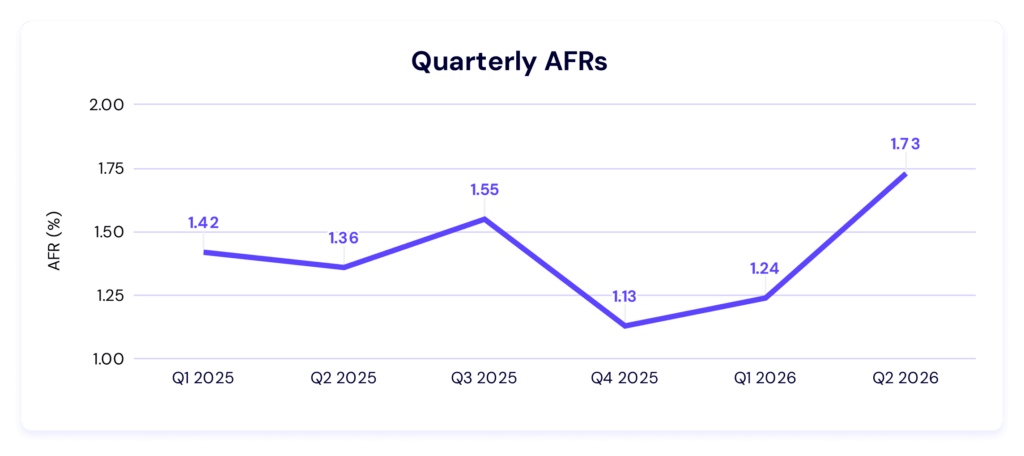
1.73
Note and observations
The quarterly AFR is 1.73%, the highest it’s been in quite a while. We’ll talk about the reasons why in just a bit, but for now, here’s your quarter-over-quarter tracking of the failure rate:
As usual, let’s round up the honor roll. These drives had zero failures:
Seagate ST8000NM000A (8TB)
Seagate ST12000NM000J (12TB)
Seagate ST14000NM000J (14TB)
And these drives had one:
Seagate ST16000NM000J (16TB)
No typos here, folks: that’s a clean sweep by Seagate.
Out with the old. This quarter, we’ve seen two drives fully retire, the 4TB HGST HMS5C4040BLE640 at nearly nine years old total; and, the 8TB HGST HUH728080ALE600 at nearly eight years old.
But where is the new? Just like last quarter, we have no new drive models—a curiosity, especially to have that happen two quarters in a row. But, also like last quarter, that doesn’t mean no new deployments. While most drive models’ counts stayed more or less the same (plus or minus replacements), we once again see deployment concentrated in the 20TB+ drives.
What’s going on with the high-end outliers?
This quarter we had three outliers, which, according to a quartile analysis, defines an outlier as an AFR above 6.95%. Those drives are:
HGST HUH721212ALN604 (12TB)—7.63%
Seagate ST10000NM0086 (10TB)—9.33%
Seagate ST14000NM0138 (14TB)—8.26%
Each of these drives have some pretty clear reasons for high failure rates. The HGST drive is nearly seven years old, and the 10TB Seagate was nearly 8.5 years old.
Meanwhile, both the Seagate drives have a pretty low drive count—the 10TB drive only has 965; whereas the 14TB has 1,235. That means that while they only had 22 and 25 failures (respectively) their AFRs were quite high.
It’s worth noting there were a total of seven drives that still had an AFR of >3.0%. While we’ve just determined those aren’t outliers, that’s still quite a few high AFRs compared to other quarters—that means that 10 out 31 drives had an AFR higher than 3.0%.
I haven’t done a full analysis of how rare it is to have our distribution of >3.0% skew that high, but a casual look at the last few quarters show it to be skewed towards the higher end of the spectrum. That will, of course, bring up our average. Something to keep an eye on as we move forward.
Standard definitions
As mentioned, we remove drives that don’t meet our criteria. We’ve covered the reasons that we’ve designed these exclusions in past reports, but here’s the quick and dirty:
Period
Drive Count
Drive Days
Quarterly
> 100
> 10,000
Annual
> 250
> 50,000
Lifetime
> 500
>100,000
Regardless of whether or not a given drive model is included in this article’s charts and tables, all of the line item data is included in our Drive Stats dataset which you can download by visiting our Drive Stats page.
Lifetime hard drive failure rates
Backblaze Lifetime Hard Drive Failure Rates
Reporting period ending June 30, 2026 inclusive Drive models with > 500 drives and > 100,000 lifetime drive days
MFG
Model
Size (TB)
Drive Count
Avg. Age (Months)
Drive Days
Failures
AFR (%)
HGST
HUH721212ALE600
12
2,599
77.4
6,351,520
111
0.64
HGST
HUH721212ALE604
12
13,196
57.7
25,209,144
1,224
1.77
HGST
HUH721212ALN604
12
9,694
79.8
27,776,092
1,858
2.44
Seagate
ST8000DM002
8
6,903
107.3
33,679,046
1,418
1.54
Seagate
ST8000NM0055
8
13,112
97.1
46,308,955
2,515
1.98
Seagate
ST10000NM0086
10
965
92.1
3,652,808
328
3.28
Seagate
ST12000NM0007
12
972
31.7
37,413,220
2,307
2.25
Seagate
ST12000NM0008
12
18,521
69.8
44,683,877
2,612
2.13
Seagate
ST12000NM000J
12
1,079
21.5
730,603
22
1.1
Seagate
ST12000NM001G
12
13,177
62.3
26,300,571
723
1
Seagate
ST14000NM001G
14
10,498
61.2
20,975,305
795
1.38
Seagate
ST14000NM0138
14
1,235
56
2,878,064
464
5.88
Seagate
ST16000NM001G
16
35,100
43.1
47,227,179
876
0.68
Seagate
ST24000NM002H
24
9,631
12.1
3,640,687
323
3.24
Toshiba
MG07ACA14TA
14
37,171
65.4
78,387,008
2,293
1.07
Toshiba
MG07ACA14TEY
14
989
41.1
1,324,965
64
1.76
Toshiba
MG08ACA16TA
16
39,932
33.2
41,520,709
1,213
1.07
Toshiba
MG08ACA16TE
16
6,306
49.9
10,113,070
341
1.23
Toshiba
MG08ACA16TEY
16
4,857
52.1
8,475,023
564
2.43
Toshiba
MG09ACA16TE
16
905
6.1
169,812
6
1.29
Toshiba
MG10ACA20TE
20
25,270
12.1
9,324,427
202
0.79
Toshiba
MG11ACA24TE
24
9,620
5.8
1,694,377
23
0.5
WDC
WUH721414ALE6L4
14
8,635
63.5
17,127,349
254
0.54
WDC
WUH721816ALE6L0
16
2,970
52.8
4,934,292
162
1.2
WDC
WUH721816ALE6L4
16
26,827
37.2
30,895,588
471
0.56
WDC
WUH722222ALE6L4
22
45,665
19
26,618,389
423
0.58
WDC
WUH722626ALE6L4
26
7,212
3.4
736,527
17
0.84
Totals
353,041
558,148,607
21,609
1.41
Notes and observations
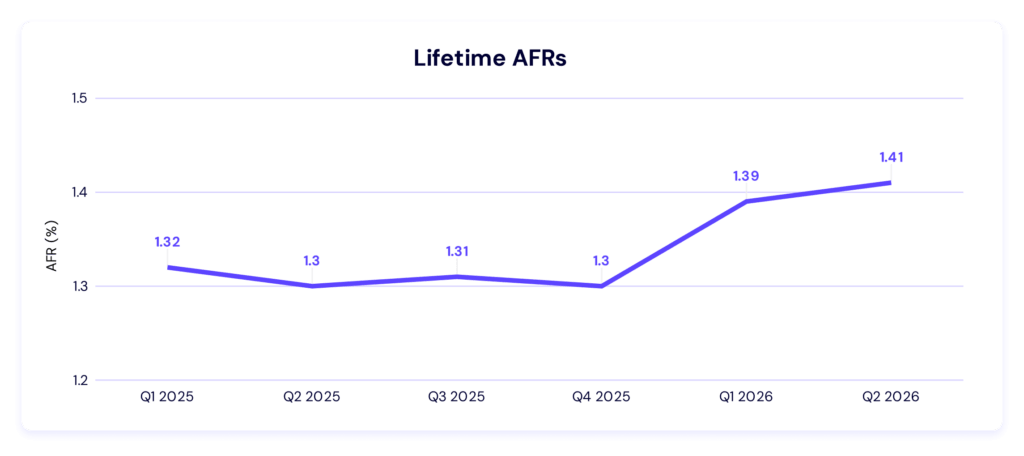
The lifetime AFR is consistent. We see a slight uptick this quarter to 1.41%.
Four models don’t make the cut on the lifetime table. These models didn’t make the drive count minimum to be reported in the lifetime table:
Seagate ST8000NM000A (8TB)—239 drives
Seagate ST14000NM000J (14TB)—497 drives
Seagate ST16000NM000J (16TB)—171 drives
Seagate ST16000NM002J (16TB)—467 drives
Interestingly, the first three on that list all were on our zero failure list as well.
About those bigger drives
Recently, we’ve spent a lot of time in this series talking about high-capacity drives. The 20TB+ club has grown from a curiosity to more than 25% of the drives in this quarter’s dataset, and deployment continues to concentrate at the larger end of the range.
As an industry, we’ve been watching the steady drive towards higher capacity drives—WD announced a 40TB UltraSMR drive just this year, with a roadmap that shows how they’ll get to 100TB by 2029. One way manufacturers are increasing that density is by changing how the tracks themselves are arranged on disk, and that has implications for how data centers read and write data. So, let’s talk about what that looks like.
CMR, SMR, and a word about roofing
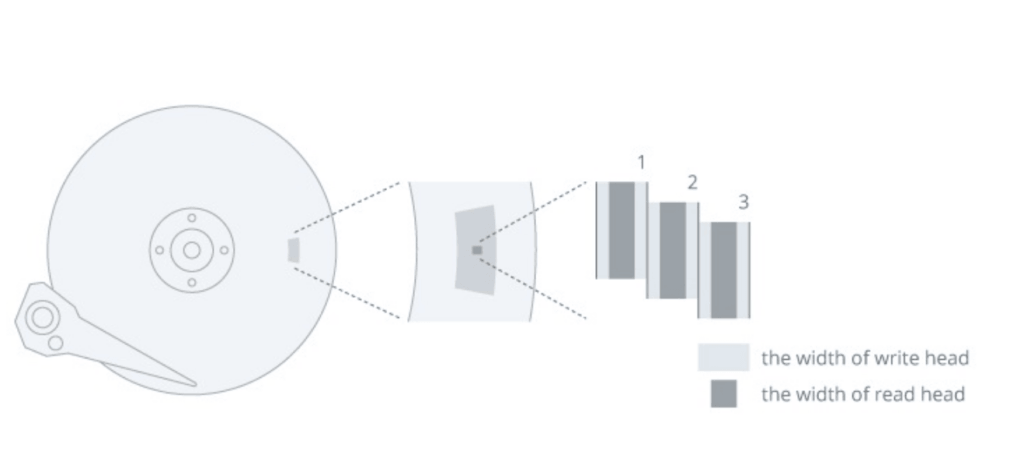
Hard drives write data in concentric tracks. Each track can be rewritten independently. Before we get into anything else, it’s important to understand that there’s a physical size difference between the read and write heads in a hard drive.
A simplified diagram of the relative sizes of read and write heads in CMR. Source.
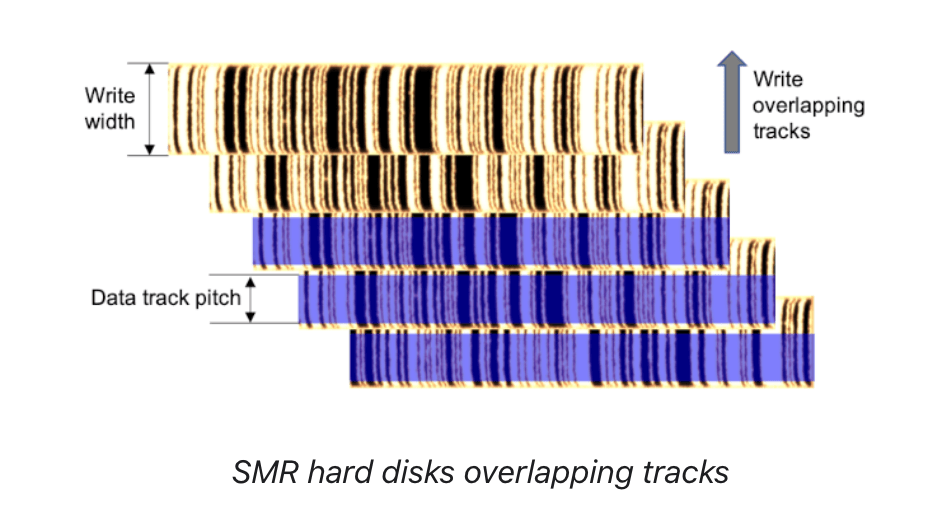
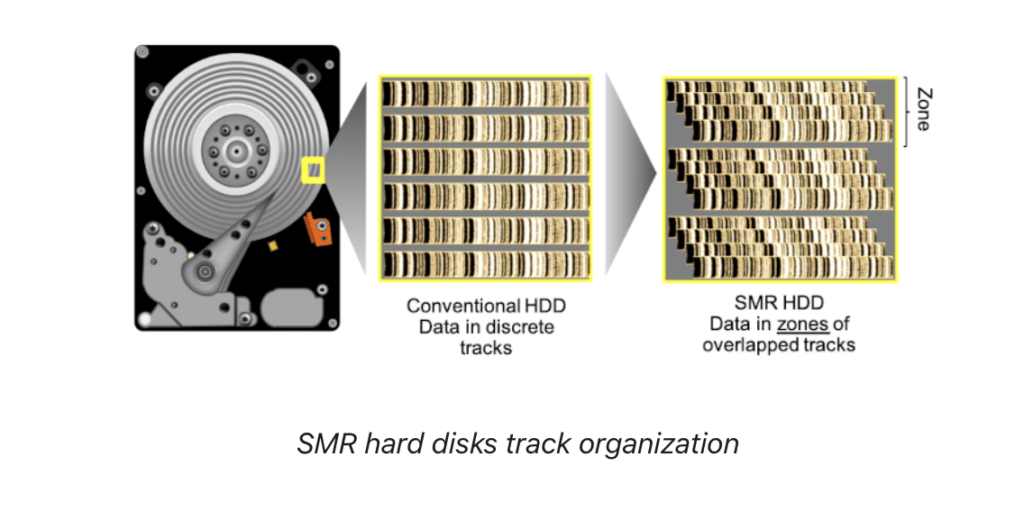
With conventional magnetic recording (CMR), those tracks sit side by side with guard space between them. Shingled magnetic recording (SMR) changes the track geometry. The tracks overlap, much like roof shingles—a naming decision that, at least for this report, we decided to really lean in on.
Now back to those drive heads: this technique works because a drive’s write head lays down a wider track than its read head needs to retrieve. Overlap part of each track with the next one and the data remains readable, while more of it fits on the platter. Depending on the implementation, that can add roughly 10% to 25% more capacity.
The tradeoff also resembles actual shingles: changing something in the middle can disturb what was layered over it. SMR organizes tracks into bands or zones, so updating data may require the drive—or the software managing it—to reorganize a larger section.
How that behavior is managed matters, so you actually will see a few different flavors of SMR:
Drive-managed SMR: The drive’s firmware handles data placement and band rewriting. It looks like a conventional block device to the host, but write performance can become unpredictable.
Host-managed SMR: The operating system or application writes data sequentially within designated zones. This requires compatible software but gives the host greater control.
Host-aware SMR: Supports SMR-aware commands while retaining some compatibility with conventional workflows.
It can be a bit hard to grasp without a visual, so here’s what that looks like in practice. Here’s an exploded version of an SMR write band:
To really nail it down (pun, as always, intended), here’s a handy-dandy table to compare:
CMR
SMR
Track layout
Side by side, with guard space
Overlapping, like shingles
Capacity on comparable platters
Baseline
Roughly 10%–25% higher
Reads
Predictable
Generally comparable
Sequential writes
Well suited
Well suited
Random rewrites
Any track can be updated directly
May require reorganizing a band or zone
Who handles the complexity
Standard storage stack
Drive firmware or SMR-aware host software
Best fit
General-purpose workloads
Sequential or append-oriented workloads
What CMR vs. SMR means in a data center
The appeal is straightforward: more terabytes per drive slot, in the same rack space, at roughly similar drive-level power. That can improve both dollars per terabyte and watts per terabyte without requiring anyone to build another building. At data center-scale, a modest density gain becomes a very large number with a dollar sign in front of it.
But, SMR cares about workload shape. Sequential and append-oriented writes play nicely with its architecture; frequent small rewrites create more work. Depending on the type of SMR, the software stack may also need to understand zones and place data accordingly.
That makes qualification less “swap the drive” and more “plan the project.” Capacity and AFR still matter, but so do sustained write behavior, rebuild performance, parity or erasure-coding overhead, firmware, and the storage software sitting above the drive.
What about HAMR?
Without making the obvious joke, let’s talk about how HAMR fits into the conversation.
HAMR is a hard drive technology that briefly heats a microscopic spot on the platter with a laser as data is written. The heat allows the drive to write to smaller, more stable magnetic grains, increasing the amount of data that can fit on each platter. And, while most hard drive platters have traditionally been built on aluminum-alloy substrates, glass is standard in 2.5-inch HAMR drives and increasingly common in high-capacity 3.5-inch HAMR designs.
Because those techniques solve different problems, manufacturers can combine them. So, the answer to “SMR or HAMR?” is mostly “yes.”
What does this mean for Drive Stats?
There are no SMR drives in the Backblaze fleet today, and none of the drives in the tables above are shingled. But SMR is being developed across the hard drive industry, and “not today” does not mean “not ever.”
We’ll approach it the same way we approached the first higher-capacity drives: as SMR drives enter the fleet, we’ll flag which ones they are, and we’ll all get to chat about their AFRs.
Get the full dataset
As always, the complete dataset used to create the tables and charts in this report is available on our Hard Drive Test Data page. You can download and use this data for free for your own purpose. All we ask are three things:
You cite Backblaze as the source if you use the data;
You accept that you are solely responsible for how you use the data, and;
You do not sell this data itself to anyone; it is free.
If you’re a new Drive Stats fan, consider signing up for the newsletter. If you’re not ready for that kind of commitment, sound off in the comments section below or reach out directly to us to let us know what you’re working on.
Neoclouds are built around GPUs, and GPUs can only run as fast as the data coming in. At the speeds AI training demands, conventional cloud storage solutions can’t keep up.
That’s where flash storage comes in. Flash is fast and reliable, purpose-built for workloads that need data delivered at extreme speed and low latency. But much of the storage work that surrounds active training—saving checkpoints, storing datasets, keeping finished models—doesn’t need flash-grade speed (or flash-grade prices).
That’s an issue for neoclouds. Their infrastructure is built around flash. So for storage that doesn’t need flash, they often point customers to hyperscaler object storage solutions instead. It’s cheaper, it works, and it keeps the neocloud focused on what it does best.
The problem is data gravity: the more data you have stored somewhere, the harder it becomes to leave. Hyperscalers make this worse by design. They let you put data in for free but charge prohibitively expensive egress fees to take it out. So once your data is entrenched on a hyperscaler’s platform, the cost of leaving keeps climbing. And wherever your data lives, that’s where you tend to buy more services. So while the neocloud keeps getting paid for GPU computing, the hyperscaler quietly takes over the broader account. What started as a sensible storage decision ends up with the hyperscaler owning everything except the GPU contract.
This article explains how a sensible storage decision can slowly hand a customer to a hyperscaler, and how a tiered storage architecture, with flash where it belongs and cheaper high-capacity storage everywhere else, lets neoclouds compete for the whole account.
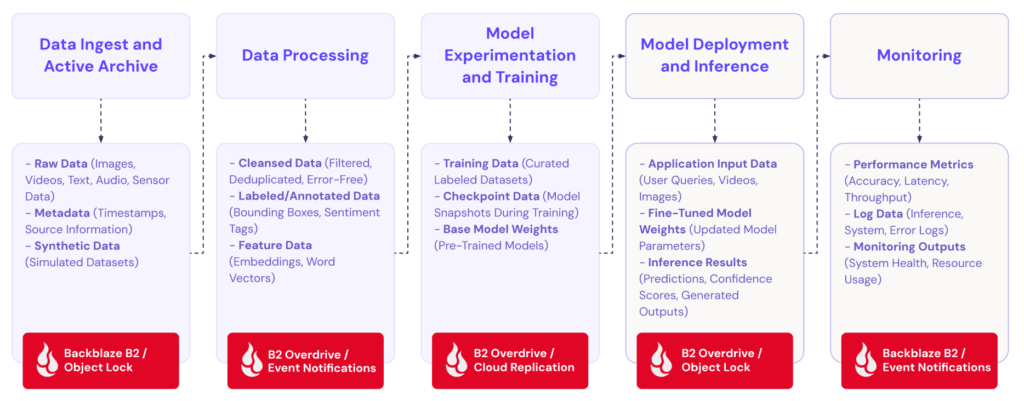
Each lifecycle stage carries a different storage profile
To see why flash alone isn’t the answer, it helps to walk through what each stage of the AI lifecycle actually needs from storage.
It starts with data ingestion. Before training begins, raw datasets have to be cleansed, labeled, and prepared. This stage needs high-capacity storage that can move large volumes of data efficiently. Speed matters, but not to the degree that flash is necessary.
Active training is the stage where flash earns its place. Data moves through several storage tiers before it reaches the GPU, but at that final step, the model needs it delivered continuously and at very high speed. Only flash is fast enough to keep thousands of GPUs running without interruption.
Checkpointing runs throughout training. Because AI training is a synchronous process with every node in the cluster working in lockstep, a single component failure can bring the entire training run to a halt. And at the scale of a large modern cluster, failures are not rare. The failure rate also scales exponentially with cluster size. Checkpoints are the solution: frequent snapshots of the model’s current state that allow training to resume from where it left off. At large scale, a checkpoint may need to capture 15TB of data in under five seconds, repeated every few minutes, around the clock. This stage needs storage that is fast enough to keep up with that pace, and reliable enough that nothing gets lost.
Once training finishes, the outputs—model weights, logs, and metadata—go into longer-term storage. Fine-tuning experiments and additional training runs add more over time. This stage needs capacity and durability, not speed.
Finally, inference: serving a deployed model requires repeated access to model weights on demand. The data volumes are far smaller than training, and while latency-sensitive deployments may still benefit from flash, the storage demands are far less intensive.
Flash storage is purpose-built for only one of these stages (active training). At every other stage, what’s needed is a cost-effective, high-capacity storage tier, which is precisely what neoclouds are currently sending to hyperscalers. (NVIDIA’s certified storage program validates storage solutions separately for each of these stages, recognizing that a single storage architecture can’t serve all of them well.)
Flash is the wrong tool for most of the job
Flash storage is expensive because it’s built for speed. But you pay for that speed whether you need it or not. Using flash to store datasets, checkpoints, and finished model artifacts is like shipping all of your mail overnight when most of it could go by ground; you’re paying a premium for a capability you don’t need.
And there’s a second problem beyond the cost. Flash that’s tied up storing checkpoints and datasets isn’t available for GPUs, and GPUs are what neoclouds sell. Every terabyte of flash used in the wrong place is capacity taken away from the core product.
The economics have always favored a tiered approach: fast storage where speed is needed, cheaper high-capacity storage everywhere else. In fact, Google, Meta, and Microsoft have run tiered storage architectures for years (Meta’s engineering team describes their approach in four explicit tiers, each selected for the job it does best).
But building out a full storage tier below flash is a significant undertaking, and most neoclouds have understandably stayed focused on their core GPU product. With SSD prices up 257% in under a year, that gap has become too expensive to ignore.
How a tiered stack maps to the lifecycle
The solution is to follow the same logic the hyperscalers have used for years: match the storage to the workload, not the other way around.
For active training, flash is still the answer. VAST, WEKA, and DDN handle this tier with fast, GPU-adjacent storage that keeps training running at full speed.
For everything else, B2 Neo can fill the gap. Datasets live here before training starts. Checkpoints write here continuously during training. Finished model weights and records accumulate here over time. The storage is fast and durable, but priced for capacity workloads rather than flash workloads. B2 Neo connects directly to the hot tier, so data moves between them without a detour through a hyperscaler.
The best part is the neocloud doesn’t have to build any of this. B2 Neo is available as a white-label product, deployed under the neocloud’s own brand. The customer only sees one seamless platform; their data stays on the neocloud’s infrastructure from raw dataset to deployed model and never touches a hyperscaler.
The full picture
Flash is the right storage for one stage of the AI lifecycle. At every other stage, it’s an expensive tool for a job that doesn’t need it.
Neoclouds that only serve the active training tier leave a gap, and customers often fill that gap by sending their data to a hyperscaler. Once it’s there, egress fees keep it there. The neocloud ends up handing the broader customer relationship to whoever holds the data.
The good news is that closing the gap doesn’t require building anything from scratch. The tiered architecture that Google and Meta run at scale is available to neoclouds today as white-label infrastructure.
In this market, the GPU contract is just the beginning. Keeping the data is what keeps the customer.
Hit a wall trying to scale your storage infrastructure? B2 Neo gets you the rest of the way there, no rebuild required. Let’s talk.
If you’ve spent any time configuring immutable backups, you’ve probably hit at least one of these moments: you thought the data was protected, something went wrong, and the protection wasn’t quite what you expected. Object lock is one of the most misunderstood features in cloud storage, and the gap between “I enabled it” and “it’s actually working correctly” is where most mistakes live.
This is a collection of the real issues that come up in technical conversations with IT administrators and system architects, the kind of problems that surface after the documentation has been read but before the configuration is fully trusted.
Locked Up: Inside a Real LockBit Ransomware Attack
Join Zach Lewis—CIO/CISO at the University of Health Sciences & Pharmacy and author of Locked Up—for a candid fireside chat on what really happens during a modern ransomware attack.
The Difference Between Immutability and Encryption
These two features often get lumped together as “data security,” but they protect against completely different threats.
Encryption protects people from seeing your data. Object lock protects people from deleting it. An encrypted backup that an attacker can wipe is not a recovery option. An immutable backup that an attacker can read in plaintext is still a usable recovery point.
Both matter. They serve different functions. Treating them as interchangeable is how organizations end up with gaps in one direction or the other.
Immutable Does Not Mean Inaccessible
This one causes real hesitation when IT teams are evaluating immutability for production backup workflows. The concern is that locking data will make it unavailable for restores.
It won’t.
Immutable data is fully readable and downloadable throughout the immutability period. You can restore from it, access individual files, and upload new versions alongside the protected ones. The only thing object lock prevents is modification and deletion before the immutability period expires. That’s the whole point.
The Bucket Creation Problem
With Backblaze B2, object lock can be enabled at bucket creation or added to an existing bucket later. Once enabled, it cannot be turned off, so the change is permanent in that direction.
That said, enabling object lock on an existing bucket does not retroactively protect the files already in it. Only files uploaded or copied into the bucket after object lock is enabled are eligible to be locked. Files that were there before are unaffected.
The practical implication: if you’re adding object lock to a bucket with existing backups, don’t assume those older files are now protected. They aren’t. New backups written after the change will be, but anything already sitting in the bucket requires individual lock settings to be applied manually.
Who Actually Configures the Retention Period
There’s a common assumption that immutability is configured at the bucket level. For many backup applications, that’s only half the picture.
When you’re using Veeam or similar enterprise tools, the backup application manages object lock on a per-file basis. The bucket needs to have object lock enabled as a capability, but the application controls which files get locked and for how long. Think of the bucket setting as opening the door; the backup software decides what walks through it.
This means both sides need to be configured. Object lock enabled on the bucket, and immutability enabled within the backup application. One without the other does nothing.
Retention Period vs. Immutability Period
These are separate settings that operate independently.
A four-year retention policy means your backup application keeps the data for four years. A 14-day immutability period means files cannot be deleted or modified for 14 days after they’re written. Once the 14 days expire, the object lock is released. The file is still there, governed by your retention policy, but it’s no longer immutable.
The two settings don’t need to match. A typical setup runs a long retention policy with a shorter immutability window. The immutability window covers the period when ransomware or a malicious actor is most likely to attempt deletion. Once that window passes, normal retention rules apply.
How Long Should the Immutability Period Be?
The most common recommendation is 7 to 14 days, with 14 days being a reasonable default for most environments.
The logic is straightforward: if ransomware or an attack hits your environment, you’re going to know within hours, maybe a couple of days. The immutability period doesn’t need to cover months of potential compromise. It needs to cover the window between when an attack occurs and when you detect and respond to it.
For most organizations, 14 days is more than sufficient. Security teams that have tested their incident response workflows often find 7 days works fine. The point is aligning the period with your detection capability, not maximizing it arbitrarily.
There’s also a cost angle that’s easy to miss. Every time backup software writes or renews an object lock, it makes a PUT-class API call to update the retention metadata on that object. On AWS S3, those calls are billed as standard PUT requests at $0.005 per 1,000. In large environments with frequent backup jobs, those transaction fees accumulate. Backblaze B2 doesn’t charge for PUT requests, so lock writes and renewals are included with your storage. In practice, this means shorter immutability windows don’t carry a cost penalty on B2, and there’s no incentive to minimize lock renewals to reduce your API bill.
Veeam Quietly Extends Your Immutability Period
If you configure a 7-day immutability period in Veeam and then check the actual lock expiration dates in your bucket, don’t be surprised to see files locked through day 10, 14, or even 17. Veeam adds extra days to the immutability period beyond whatever you configure.
This is intentional behavior. Veeam is protecting against the scenario where a file is written late in a backup job, and a retention cleanup operation would otherwise try to delete it before the immutability period has fully elapsed. The extra days create buffer.
The practical implication is storage capacity planning. If you’re budgeting for 7 days of immutable storage, you may actually need to account for closer to 14 days of data that can’t be deleted at any given time. Plan for that variance.
Don’t Set Bucket Lifecycle Rules When Using Backup Software
Bucket-level lifecycle rules that automatically delete data based on age or other criteria will conflict with how backup applications manage their own data lifecycle.
When you let Veeam or another application handle your backup chain, that application tracks which files are active, which are expired, and when each should be removed. If you set a bucket lifecycle rule that deletes files after 30 days, and your backup application is still referencing a file that’s 32 days old, you’ve broken the chain.
The right approach is to leave bucket lifecycle rules alone and let the backup software handle all data management. If your backup application is working correctly, there’s no need for bucket-level deletion rules. If something isn’t working correctly, a lifecycle rule will compound the problem.
Not All Backup Software Supports Object Lock
Consumer sync tools and basic file backup applications generally don’t support immutable backups. When they encounter an immutable object, the write operation to delete or modify it will fail, which breaks the backup job.
Enterprise backup applications like Veeam and Commvault have native support for object lock. They know how to write immutability flags, manage retention periods, and handle the S3 API calls correctly.
If your current backup tool isn’t on the enterprise list, check the documentation before assuming immutability will work. A backup chain that fails silently because of incompatible object lock handling isn’t protecting anything.
Can You Change the Immutability Period After Setting It?
You can extend it. You cannot shorten it.
Once an object is locked with a specific expiration date, that date can only move forward. This is a deliberate design constraint: the whole value of immutability is that it can’t be weakened retroactively. If a compromised account or a bad actor could shorten or remove the lock, the protection would be meaningless.
The same principle applies to governance mode versus compliance mode configurations. Compliance mode makes data deletion impossible even for account administrators during the retention period. Governance mode allows certain privileged users to modify the lock. For serious ransomware protection, compliance mode is generally the stronger choice.
What Happens If Someone Deletes the Account?
This is the limit of what object lock protects against, and it’s worth understanding clearly.
Object lock prevents any individual from deleting immutable objects within your account. Even an administrator with full permissions cannot delete a locked object before its retention period expires.
However, if someone with account-level access deletes the entire account, that protection doesn’t save the data. This applies to every cloud storage provider, not just Backblaze. It’s not a gap in object lock, it’s a different attack surface entirely.
The mitigation here is account security: two-factor authentication, limited administrative privileges, and monitoring for unusual account activity. Object lock and account security work together. Neither one makes the other redundant.
Does Immutability Cost Extra?
With Backblaze B2, no. Immutability is included as part of the standard storage subscription.
This is worth noting because some storage providers charge separately for object lock API calls, including the PUT requests that renew or write lock metadata. Those transaction fees can add up significantly in environments with high file counts or frequent lock renewals. With B2, you pay for the storage you use, including any additional storage consumed by data that can’t be deleted during its immutability period. The feature itself has no surcharge.
Versioning and Storage Costs
If you enable versioning alongside immutability, all versions of a file count toward your storage usage, not just the current one. If a file has been modified 50 times and you’re storing 50 versions, you’re paying for all 50 regardless of how many of them are currently immutable.
This is consistent across cloud storage providers and is the tradeoff for having granular recovery options. The right versioning configuration depends on your recovery objectives and your budget. Keeping every version indefinitely is rarely necessary. Most backup applications give you control over how many versions to retain, and that setting directly affects your storage costs.
What to Do Before You Deploy
A few things worth confirming before putting object lock into production:
First, verify that your backup application has native object lock support and that you’ve enabled immutability within the application settings, not just at the bucket level.
Second, create your bucket with object lock enabled even if you’re not planning to use it on day one. You can’t go back and enable it later.
Third, skip bucket lifecycle rules if your backup software is managing the data lifecycle. Let the application do its job.
Fourth, account for Veeam’s extra days when planning storage capacity. The actual locked window will be longer than what you configure.
Fifth, review your immutability period in the context of your incident detection capability. A 30-day immutability window isn’t more secure than a 14-day window if your security team can detect an incident within 48 hours.
Object lock is one of the more reliable tools available for protecting backup data against ransomware. It does what it claims. The configurations above are where implementations go wrong, and most of them are easy to get right once you know where to look.
Ask any IT director managing a Mac fleet above 50 devices what they need from a backup tool and you’ll hear the same answer before you finish the question. Silent install. Jamf deployment. No prompts. No user interaction. The requirement has been on every evaluation checklist for years, but something has shifted: IT teams have stopped treating it as a preference and started treating it as a filter. Either a tool deploys cleanly through their MDM or it doesn’t make the shortlist. Full stop.
This isn’t pickiness. It’s the only logical position for teams managing hundreds of machines with two or three people.
The Adaptation Problem
Most backup software was built for Windows. The Mac client came later, ported and adapted to work. That history shows up in ways that don’t matter much in a consumer context but matter enormously in a managed fleet.
Mac IT teams running Jamf Pro, Kandji, or Addigy have built their entire operating model around scripted automation. They don’t log into machines. A new hire’s laptop is enrolled, configured, and production-ready before the person sits down. Software appears on machines through policy, not support tickets.
When backup software was designed for a world where someone clicks through an installer, it fights that model at every step. Permission dialogs surface on end user screens. Enrollment fails to register under the provisioned account. The agent installs but doesn’t actually start backing up. Each of these is a support ticket at minimum and an unprotected machine at worst. The IT team ends up owning a third-party deployment problem indefinitely, patching around a script that should have worked out of the box. That’s where Windows-first adaptation gets you.
The Mac backup market has also thinned out in ways that matter. Several vendors that once had credible Mac products have wound down, been acquired, or shifted focus to enterprise platforms where Mac support is a checkbox rather than a priority. Teams that built workflows around those products are now evaluating replacements, often under time pressure, and finding that the field of tools that actually understand Mac MDM is narrower than it looks.
What Silent Actually Means
“Silent install” appears in the marketing materials of practically every backup vendor. It means different things to different people.
For most Mac admins, truly silent means the agent installs, configures itself, handles all required system permissions through MDM profiles, registers under the correct provisioned user, and starts backing up, without a single prompt appearing on the end user’s screen and without any post-install action required from IT. Nobody knows it happened. Nobody has to do anything.
The gap between that definition and what some vendors deliver is where fleet coverage breaks down. Full disk access approvals that surface as user-facing dialogs. Kernel extension prompts that require user confirmation. Background item notifications that confuse employees and generate help desk calls. Each of these seems minor in isolation. Across a 300-machine fleet during a busy onboarding week, they add up to a coverage gap you won’t discover until someone needs a restore.
When it works correctly, employees never know it’s there. Nobody files a ticket about it. Nobody asks IT what the new icon is. That’s the bar.
Backblaze Computer Backup deploys silently through Jamf Pro, Kandji, Addigy, and other MDM platforms via CLI scripts. Pre-built deployment scripts are available on GitHub. Full disk access and system permissions are configured through MDM profiles pushed alongside the agent, with no end user interaction required and no post-install steps for IT. For most Jamf environments, the pre-built script requires nothing more than editing a few variables before it’s ready to push.
There’s also a pricing angle here that doesn’t come up enough: backup tools that require manual or user-assisted enrollment tend to leave machines uncovered. Machines that aren’t backed up still cost money in the per-seat model. You’re paying for protection that isn’t running. With flat per-device pricing and no storage-based overages, there’s no financial incentive to under-enroll, but the only way to ensure complete enrollment is deployment that doesn’t depend on human action.
When Coverage Gaps Cost Real Money
The efficiency argument for zero-touch deployment is intuitive. The cost argument is less obvious until something goes wrong.
A firmware bug bricks five machines. A designer spills coffee on their laptop two days before a pitch. A ransomware event starts encrypting files on devices that weren’t fully enrolled because someone skipped the setup step during a chaotic onboarding month. In every case, the recovery outcome depends on one thing: whether that specific machine was actually backed up.
Professional data recovery for a single device can run anywhere from $1,500 to $5,000 for physical damage scenarios, and that’s before factoring in downtime. For an organization that hits two or three incidents in a year, that’s real budget, often more than the cost of backing up the entire fleet. The backup subscription would have cost a fraction of that, but only if the machines were enrolled. That’s the variable zero-touch controls.
It’s also worth noting what happens to data when employees leave. Organizations with any compliance exposure, and that’s most of them, need endpoint data preserved at offboarding, not just when hardware fails. A deployment model that requires user action to complete enrollment is also a model where departing employees can have gaps in their backup history, exactly when you need it most. Legal Hold is part of the picture here: knowing you can freeze and preserve a former employee’s data only matters if their machine was backed up in the first place.
How Torcon Protects Data Wherever Work Happens
From unreliable jobsite Wi-Fi to laptops damaged by bulldozers, Torcon’s IT team faces some unusual backup challenges. See how Backblaze Computer Backup protects employees across 20–40 active construction sites—and has supported more than 100 successful recoveries.
A single-office organization can paper over a bad deployment model with physical presence. Somebody can walk the floor during an onboarding week and catch machines that didn’t enroll. Distributed teams don’t have that option.
If a new hire in Buenos Aires starts on Monday, nobody from IT is walking to their desk on Tuesday to finish a backup enrollment. The same is true for remote employees across time zones, contractors working from client sites, or a newly acquired office that runs through a separate MDM instance. The tool has to work identically everywhere without requiring a different procedure for each location.
This is where the single-account, multi-group model matters. Backblaze Computer Backup lets distributed organizations manage devices across regions under one account, with separate groups reflecting different offices, compliance zones, or MDM environments. Data residency requirements, increasingly common for organizations with EU presence, can be addressed by running region-specific accounts while maintaining unified admin visibility. The deployment script doesn’t change based on geography. The admin experience doesn’t change based on which MDM platform enrolled the device.
The Evaluation Question Nobody Asks First
Most backup evaluations start with features or pricing. That’s backwards for Mac fleets.
The right first question is: show me the deployment documentation. Ask whether the install is truly silent or requires any user-facing steps. Ask what happens when the script runs on a machine that’s already enrolled. Ask whether the same approach works across different MDM platforms. Ask for a reference from a customer running a comparable fleet size.
If a vendor built their product for Mac fleet management, those answers come quickly and confidently. If they built for Windows and adapted, the answers tend to involve workarounds, known issues, or a suggestion to open a support ticket.
Zero-touch Mac backup deployment isn’t a differentiator anymore. It’s the entrance fee. Any tool that can’t clear that bar is asking you to manage a backup system on top of managing your fleet, and that’s not a trade-off a lean IT team can afford.
See how Backblaze deploys across Mac fleets through Jamf, Kandji, and Addigy.
Backblaze Computer Backup with Enterprise Control supports silent deployment through Jamf Pro, Kandji, Addigy, Microsoft Intune, and other MDM platforms via CLI scripts. Pre-built deployment scripts are available on GitHub.
Announcing a new integration between Backblaze B2 and Suite Studios’ S3 Native File Streaming that brings together scalable object storage and the familiar experience of working from a local drive.
Available today with Backblaze B2, the integration allows teams to mount a B2 bucket through Suite Studios and work with files as if they were stored on a high-performance NAS. Suite streams only the parts of each file an application needs, rather than requiring users to download entire datasets first.
Behind that experience, the data remains in Backblaze B2 as standard S3-compatible objects.
Ready to get started now?
To put Suite S3 Native to work on B2, contact Backblaze Sales or your Backblaze reseller partner. We can help validate your architecture, plan a proof of concept, and evaluate migration support for your existing data.
Your B2 bucket becomes the working file space
An existing Backblaze B2 bucket can now be used directly as a Suite file space. There is no separate storage environment hidden inside Suite and no proprietary segmentation happening in the background.
The relationship between the file system and the bucket remains straightforward:
One file in Suite maps to one object in B2.
The folder structure in Suite matches the structure in the bucket.
Files remain standard, whole objects.
B2 remains the system of record.
Suite provides the high-performance file access layer.
For users, cloud storage behaves more like a shared NAS experience. For IT, the underlying data remains in a storage platform the organization owns and controls.
If your files are already stored in B2 as standard objects, Suite can connect to the bucket and make them available through its mounted drive. There is no need to create another copy, convert the data, or run a separate ingest into Suite.
One dataset, multiple ways to use it
The immediate opportunity is media production, where teams work with large files across editing, media management, transcoding, automation, archive, and distribution.
An editor can open high-resolution media in Adobe Premiere Pro through the Suite drive. At the same time, iconik or another MAM can index the library, Telestream Vantage can process the source files, and automation can respond to new objects written into B2.
Each application works with the same underlying media.
But this is not exclusively a media workflow. The same model has practical applications anywhere teams need to work with large cloud datasets through file-based desktop tools:
Life sciences and biotech: Make genomic sequencing, microscopy, medical imaging, and instrument-generated data accessible to researchers without maintaining full copies at every location.
Geospatial and earth observation: Work with satellite imagery, drone captures, LiDAR scans, and GIS datasets while keeping source files centrally stored.
Engineering and design: Give teams file-based access to CAD assemblies, simulations, 3D models, digital twins, and high-resolution scans.
Research and higher education: Create shared access to large scientific datasets for distributed teams while maintaining a common storage foundation.
These are emerging applications for the architecture rather than packaged Suite solutions today, but the underlying opportunity is clear: Large datasets become much more useful when people and applications can access them without moving them into another storage silo.
Built for active data
Media, scientific data, and geospatial imagery rarely sit still. Files are opened, reviewed, processed, moved, analyzed, and shared throughout their lifecycle.
Backblaze B2 provides always-hot, S3-compatible object storage with straightforward pricing and free egress up to three times average monthly storage, plus unlimited free egress through select CDN and compute partners.
That makes B2 a strong foundation for data that needs to remain active and accessible. Suite adds another way to put that data to work by making a B2 bucket accessible through a high-performance file interface.
Available today, with migration support
Backblaze B2 is available today for Suite S3 Native workflows.
If your data is already in B2, you can use an existing bucket as your Suite file space. If it currently resides in another cloud, on a NAS or SAN, or on tape, Backblaze can help plan and execute the move.
Organizations making a qualifying commitment can receive assisted migration into B2 through our Universal Data Migration program.
Bring the data into the storage platform you want to keep. Let cloud applications access it through S3. Let people access it through a high-performance drive.
One dataset. One storage foundation. Multiple ways to put it to work.
AI agents are getting very good at making things: reports, code builds, images, videos, datasets, customer exports, and backups. But generating a file is only half the job. The agent still needs somewhere durable to put it. That’s where B2 comes in.
Today, we’re introducing the Backblaze B2 MCP Server: an open source server that gives AI agents a safe, standard way to operate cloud object storage.
Introducing the Backblaze B2 MCP Server
Model Context Protocol (MCP) provides a common way for AI agents to discover and use external tools. The Backblaze B2 MCP Server applies that model to Backblaze B2 Cloud Storage, connecting MCP-compatible clients to a focused set of storage operations.
The server is open source and designed so the tools presented to the agent reflect the permissions of the connected B2 application key.
And that last point is important. The MCP server does not invent a new permission model or grant an agent blanket access to your account. If the key can only read from one bucket, the agent’s usable tool set and reach are constrained accordingly. If the key does not permit an operation, the agent cannot use the MCP server to bypass that boundary.
Why launch an MCP server?
Storage has always met developers in two places: the API and the console. Agent tools are becoming a third, and increasingly the one where work starts. Our view is that infrastructure should be available inside the tool someone already has open, at the moment they need it.
That spans a wide range of work: everyday tasks that produce outputs which need to be stored, AI workflows that read and write data as they run, and applications that require storage to handle files. A report or an export has to land somewhere durable. An application built around agents needs somewhere to put user uploads, generated assets, and datasets. Customers have also asked us how their own agents can administer their storage.
MCP is what lets one implementation serve all of it. An MCP server provides these storage tools directly to the AI agents people use for everyday tasks and for coding, so the same credentials, scoping, transfer path, and destructive operation policy apply everywhere your team works. B2 is available inside the tools your teams already have open.
See it in action
Suppose an agent has prepared a customer export. Instead of handing it a general-purpose credential and writing the surrounding storage logic yourself, you could ask:
“Prepare a private destination for this customer export. Keep it for 30 days and give me a secure way to upload it.”
Depending on the application key’s permissions and the server’s policy settings, the agent can:
Create a private bucket or select an existing one the key can access.
Apply lifecycle or retention settings, depending on whether the export should expire automatically or be protected from deletion.
Generate a short-lived upload URL.
Verify that the export arrived.
Return a short-lived download URL to the intended recipient.
For a large export, the bytes move directly to B2 using the short-lived URL; they do not need to pass through the model conversation or the MCP server. That keeps bulk data on the right path and leaves the agent responsible for orchestrating the work, not hauling the payload.
Now imagine a follow-up request: “Delete that export.” The B2 MCP Server can require confirmation before the action proceeds or block destructive operations entirely, depending on how the server is configured. The same principle applies to changes that weaken protection, such as clearing retention or introducing lifecycle rules that schedule deletion.
The result is a useful division of labor: The agent can set up the storage, move the file, and verify the outcome, while the B2 MCP server enforces the connected key’s limits and configured policy.
Built for real storage work
The B2 MCP Server includes up to 40 tools across the B2 Native API, B2’s S3 Compatible API, and purpose-built storage analytics. You do not need to expose all of them to every agent. The available surface adjusts to the connected key and the server’s policy settings.
Manage storage. Create and configure buckets, list and manage objects, define lifecycle rules, work with retention and legal holds, and use Object Lock where the workflow calls for stronger protection.
Move large files directly. Generate short-lived upload and download URLs, or use multipart transfers for large objects, so bulk data stays out of the model and MCP server.
Limit access. Connect a scoped B2 application key so the agent can see and use only the buckets and capabilities it needs. For normal storage work, a non-master key is the right starting point.
Gate destructive actions. Set the destructive-action policy to require confirmation, block the operation, or allow it in a trusted environment. Local use defaults to confirmation; hosted HTTP deployments default to blocking these calls.
Inspect usage. Find storage growth, identify egress leaders, locate the largest files in a bucket, and surface unfinished multipart uploads that may be consuming storage.
Safety starts with the key
An MCP server makes tools available to an agent; it should not make good access controls optional. With B2 MCP, the connected application key remains the first boundary. B2 application keys can be limited by bucket, capability, file prefix, and duration, giving developers a practical way to apply least privilege to agentic workflows.
The server adds another layer around operations that deserve friction. Destructive and protection-weakening actions can require an explicit confirmation or be refused before execution. For hosted deployments, the project includes additional controls and deployment guidance for credential handling, authentication, allowed hosts and origins, rate limits, and logging.
The goal is not to pretend an agent can never make a bad request. It is to give developers clear, enforceable boundaries around what the agent is allowed to do.
Already use B2? Your agents can use it too
If your application data, backups, media, or archives already live in B2, you do not need a separate storage product for agents. The MCP server works with standard B2 application keys and existing buckets.
You can connect an existing key, but in most agentic workflows it is worth creating a narrower key for the job. A reporting agent might need read access to a specific prefix. An export workflow might need permission to write to one private bucket and generate a short-lived download link. A cleanup agent might need list access but no delete capability until a human approves the action.
Try the B2 MCP Server
One-click install (Claude Desktop)
Download b2-mcp.mcpb from the latest release and double-click it. Claude Desktop opens, offers to install the extension, and prompts for your Application Key ID and Application Key (Region and master key optional) — no config file to edit, nothing pasted into the conversation. (If your system hasn’t associated .mcpb files with Claude Desktop yet, open Settings → Extensions and install it from there, or drag the file onto that window.)
Run with npx (any MCP client)
You need three things to get started:
A supported Node.js runtime.
A B2 application key. Use a non-master key and scope it as narrowly as the workflow allows.
An MCP-compatible client.
The fastest way to run the server is with npx:
`npx -y @backblaze-labs/b2-mcp`
For Claude Desktop, add the following block to claude_desktop_config.json, substitute your application key values, and restart the client:
Do not paste the application key into the model conversation. Keep it in the client configuration or your deployment’s secret-management layer.
Then try a deliberately simple first prompt: “List the buckets this key can access.”
For copy-and-paste setup instructions for Cursor, VS Code, Cline, Windsurf, Zed, Continue, Goose, Claude.ai, and hosted deployments, see the client setup guide.
See the B2 MCP Server in action. We’ll set it up, run a complete storage workflow, explain the safety boundaries, and answer your questions.
A safe way for agents to operate storage
Agents need more than somewhere to put files. They need a safe way to operate storage: to prepare the right destination, move data on the right path, verify the outcome, and stop when a request exceeds their permissions or policy.
The Backblaze B2 MCP Server brings those capabilities to the MCP clients developers are already using, while keeping B2 application keys and server-side safeguards in control. Try it with your existing B2 storage, or join the webinar to see the complete workflow.
Broadcast production has spent decades organizing media around files, servers, and the physical limits of the facility. That model is familiar, and it works until a live event creates hours of footage across multiple cameras, editors are distributed, the archive is growing by petabytes, and every copy of every clip becomes another operational and financial problem.
Time Addressable Media Store, or TAMS, offers a different model: Organize media by time, store it in object storage, and let interoperable tools access the same content through an open API. Pair that with affordable, high-performance storage, and the result is a practical path toward cloud-native production without forcing media teams into a single vendor’s ecosystem.
That is where a stack built on Backblaze B2, together with TAMS ecosystem partners LiveWyer, CuttingRoom, and Drastic Technologies, gets interesting.
What is TAMS?
When a live event is producing hours of footage across multiple cameras, editors should not have to wait for files to close before they can start working. TAMS, or Time Addressable Media Store, addresses that problem by organizing media around the timeline rather than individual files.
With TAMS, media is stored as timestamped segments that applications can access by time. A news editor can pull a quote from a press conference while it is still underway. A sports producer can create a highlight from a live game feed. A content team can reuse the same moment for social clips, a longer edit, distribution, and archive without creating a separate proprietary copy for every stage.
TAMS gives ingest systems, browser-based editors, desktop NLEs, MAMs, and archive platforms a common way to work with the same media. The store can run on one cloud, ingest can come from another provider, and editors can use the tools they already know.
The specification grew out of BBC Research & Development’s work on cloud-native media production and was published in 2023. Its purpose was practical: Give different companies a shared interface for building interoperable media workflows instead of recreating isolated storage silos in the cloud.
TAMS is not a replacement for an NLE, MAM, ingest system, or archive. It is the layer that helps those systems work together. In this article, we are focusing on three Backblaze ecosystem partners that demonstrate that approach: LiveWyer, CuttingRoom, and Drastic Technologies.
The solution stack
LiveWyer provides TAMOSS, a Kubernetes-native implementation of the TAMS API. TAMOSS is the store management and API layer. It handles the TAMS structure while orchestrating the underlying media segments stored in Backblaze B2.
CuttingRoom brings an editorial-grade video editing experience into the browser. In a TAMS workflow, editors can begin working with media while a live event is still being captured. They can find a moment on the timeline, create a clip, and assemble a story without waiting for an entire file to close or moving the media into a separate editing silo. The CuttingRoom solution allows real-time collaboration, import and exports from and to market leading MAMs and with the optional ShortCut AI assistant editing, editors can do more in less time.
Drastic Technologies’ NetX platform provides the TAMS-compliant readers and writers that handle both ends of the media flow: ingesting and writing media into TAMS, then reading it back for playback and use in professional applications such as Adobe Premiere and Avid. NetX is a key part of making TAMS flows usable across live ingest, playback, and established desktop production workflows including Adobe Premiere.
With Backblaze B2 providing the S3-compatible storage foundation beneath the workflow.
TAMOSS supplies the TAMS interface. CuttingRoom provides the browser-based editorial experience. Drastic NetX handles the critical ingest, writing, reading, and playback paths. B2 stores the media segments at a price that makes large-scale access practical.
These companies are part of a growing ecosystem of roughly 14 technology providers with publicly identifiable TAMS implementations, products, readers, writers, or integrations. That broader ecosystem includes AWS, Konstrukt, LOGIC media solutions, LucidLink, Mimir, Reuters Imagen, Matrox Video, Mavis, Norsk, Techex, and Zixi, alongside LiveWyer, CuttingRoom, and Drastic Technologies.
This is the broader idea behind an interoperable standard. No single company has to provide every part of the workflow, and customers do not have to replace every system they already own.
Where TAMS fits
The use cases are not limited to national broadcasters.
A news organization could ingest a live press conference, let an editor find a quote while the event is still happening, and publish a short clip before the full recording is finished.
A sports production team could create proxy media for immediate clipping while retaining higher-resolution source material for finishing. This is particularly useful because some high-resolution MOV and MXF workflows are difficult to segment and read while they are still growing.
A regional sports league or smaller event producer could avoid building a large on-premises storage environment and give remote editors access to the same media from wherever they are working.
A corporate video team could record a town hall, create short internal clips, publish social content, and retain the full event in the archive using the same underlying media.
The same approach could support houses of worship, education, government, live entertainment, and creator workflows. The common requirement is quick access to a growing body of media without multiplying copies and handoffs.
What if the editor reviewing a live feed did not need to ask where the file was? What if the answer were simply a time range in a shared store?
Why Backblaze B2 matters
Live video is a storage problem before it is almost anything else. A multi-camera sports event, a continuous news operation, or a large livestream can generate terabytes of content quickly.
Backblaze B2 starts at $6.95 per terabyte per month, with free egress up to three times average monthly storage and no egress fees through many compute and CDN partners. That combination makes it easier to keep large live datasets available for editing, review, distribution, and archive.
A TAMS workflow backed by B2 can look like this:
– Use Drastic NetX to ingest and write live feeds into a TAMS store.
– Segment and index the media as it is captured.
– Let editors begin clipping and assembling stories in CuttingRoom.
– Use NetX readers to play and access the same media from Adobe Premiere or Avid.
– Keep the objects available for near-live production, distribution, and archive.
– Add a MAM where richer search, rights, governance, and catalog workflows are required.
Our deployment test offered one final lesson. Getting media into the store was straightforward. Making the service usable by the rest of the team required attention to the operational details. Open standards reduce lock-in, but production still depends on good deployment practices.
That is a healthy place for the industry to be. The pieces are becoming more modular, the interfaces are becoming more open, and media teams have more freedom to assemble the workflow that fits them.
TAMS gives those tools a common language. TAMOSS makes the store deployable. Drastic NetX handles how media is written into and read from the workflow. CuttingRoom makes the content useful to editors and production teams. And Backblaze B2 provides a scalable storage layer that makes the economics work.
The question is no longer whether live media can be stored in the cloud. It is whether we can make that media available to the right person, in the right tool, at the right moment.
Your Code42 renewal notice showed up with different news this year. New sales stopped at the end of 2025. Support ends at the end of 2026. After that, your backup archives get deleted.
So you start looking for a replacement, and the first name that comes up is CrashPlan.
Makes sense. Same lineage. Familiar interface. Probably assumes it’s the safe, low-effort choice, since it’s basically still Code42, right?
Not quite. And that assumption is worth slowing down on before it makes the decision for you.
CrashPlan and Code42 stopped being the same company in 2022
Code42 didn’t rebrand into CrashPlan. It sold it.
In 2022, Code42 spun off its backup business to Mill Point Capital, a private equity firm, and kept the name Code42 for what remained: Incydr, its insider risk and data loss prevention product. The backup product you knew went with the spinoff and became CrashPlan Group, a separate company under separate ownership with its own board, its own P&L, and its own reasons for making decisions.
Code42 itself was later acquired by Mimecast, which is why the backup add-on still bundled with Incydr is now the thing getting discontinued.
Two different companies. Two different endings. One of them just happens to still have “Code42” written all over your IT team’s institutional memory.
Why that matters more than it sounds like it should
If CrashPlan were still part of Code42, you could reasonably treat this as an internal product transition. A new plan, maybe a new UI, but the same company standing behind the decision.
It isn’t that. CrashPlan is a separate company that stands to gain from every Code42 customer who defaults to them without comparing alternatives. That’s not a knock on CrashPlan. It’s just how the incentive is built. A company selling you the “next step” isn’t the same thing as a neutral party recommending your best option.
Which is exactly why CrashPlan has built migration tooling specifically aimed at capturing displaced Code42 customers. It’s a smart move on their part. It’s also a reason to look closer, not a reason to skip the evaluation.
The 5TB cap nobody’s mentioning
Here’s something worth checking before you assume CrashPlan is a like-for-like replacement: some of its plans now cap storage at 5TB.
If you were on Code42 for straightforward, unlimited endpoint backup, that’s a meaningful change, not a rounding error. Plenty of IT teams don’t find out about a storage ceiling until they hit it, usually mid-migration, usually at the worst possible time to discover a gap.
Ask directly. Get the number in writing. Don’t assume “backup” means the same thing across two different companies just because one of them used to own the other.
“Enterprise data resilience” is not the same pitch as “backup”
CrashPlan has also been repositioning its messaging, moving from straightforward backup language toward broader “enterprise data resilience” positioning.
That’s not necessarily bad. It might be exactly what some organizations need. But it’s a different product story than the one you signed up for with Code42, and different stories tend to come with different pricing, different complexity, and different things bundled in whether you asked for them or not.
If what you actually need is dependable endpoint backup, a platform that’s busy becoming something bigger isn’t automatically the simpler choice. Sometimes it’s the more expensive one wearing a more ambitious name.
The question worth asking before you default to anything
Not just about CrashPlan. About whatever you’re evaluating next.
Who owns this company, and what are they optimizing for? What happens to my data and my pricing if this company gets acquired, repositioned, or sunset the way Code42’s backup product just was? Is this the vendor I’m choosing on the merits, or the one I’m choosing because switching again sounds exhausting?
That last one is real, and nobody should pretend it isn’t. Migration fatigue is a legitimate reason people make worse decisions than they would otherwise. It’s also exactly the moment worth a second look, not a shortcut.
What we’d suggest instead
Compare CrashPlan against your actual requirements, not against the assumption that it’s the default successor. Ask about storage limits in writing. Ask what “enterprise data resilience” costs versus what plain backup used to cost. And give yourself enough runway to compare more than one option, because a rushed decision made under a vendor’s deadline is usually the vendor’s deadline working exactly as intended.
If you want a second option in that comparison, we put together a migration guide that walks through what a Code42 replacement looks like on Backblaze specifically, including a realistic week-by-week timeline that doesn’t leave you without protected data at any point in the switch. Backblaze Computer Backup runs a lightweight native client and deploys silently through the MDM tools most IT teams already use, so the evaluation itself is quick even if the decision takes longer. It’s not the only option out there. It’s just one worth putting next to the others before you pick anything.
Migrating off Code42 and want to see how the timeline actually works? Talk to our team about what it would take to move your environment to Backblaze.
Always-on SSE-B2 brings AES-256 encryption at rest to every new upload and destination copy—with no application changes, additional cost, or performance impact.
Security works best when it doesn’t depend on one more checkbox. Starting September 14, 2026, we’re making server-side encryption the automatic baseline for Backblaze B2 Cloud Storage.
Backblaze B2 will automatically encrypt all newly uploaded and copied object data at rest using Server-Side Encryption with Backblaze-managed keys (SSE-B2) and AES-256. The default applies immediately to new buckets. Existing buckets will receive the default gradually; once enabled for a bucket, newly uploaded and copied objects use SSE-B2 automatically. If an application doesn’t specify an encryption method, B2 handles it automatically.
Here’s the TL;DR: You don’t need to update your application, add an encryption header, or turn on a bucket setting. There is no additional charge for SSE-B2 and no impact on upload or download performance. New uploads are encrypted by default, existing objects keep their current encryption state, and SSE-C remains available when you want to provide your own key for an individual object.
Secure by Default, Without Extra Work
SSE-B2 encrypts object data at rest with AES-256 while Backblaze manages the encryption keys. Until now, customers could choose to enable SSE-B2 for a bucket or request it for an individual upload. With always-on encryption, SSE-B2 becomes the baseline for every new upload and destination copy when SSE-C is not explicitly requested.
That means fewer settings to manage, fewer opportunities for configuration drift, and a stronger security baseline across your storage environment. Teams can meet encryption-at-rest requirements without building another check into every application or deployment process. Server-side encryption cannot be disabled for new writes.
For new buckets, the default applies immediately. Existing buckets receive it gradually; once enabled for a bucket, new uploads and destination copies receive SSE-B2 automatically. Buckets already configured for SSE-B2 remain configured as they are, and requests that explicitly use SSE-C continue to use SSE-C.
What This Means for Your Existing Workflows
The best kind of security improvement is one that doesn’t force you to rebuild what already works. Always-on encryption is a behavioral update, not a new API contract. Existing integrations can keep using the same upload, copy, multipart-upload, and download operations they use today. B2 automatically decrypts SSE-B2 data for authorized reads, so the way you access objects does not change either.
See the Default in Action
The important part of these examples is what is missing: Neither upload explicitly requests SSE-B2. After this update, Backblaze applies it automatically.
S3-Compatible API: Upload Without an Encryption Flag
There is no --server-side-encryption option in the command. B2 still encrypts the new object with SSE-B2. In S3-compatible responses, that effective encryption is represented as AES256.
# Response includes "serverSideEncryption": {"mode": "SSE-B2", "algorithm": "AES256"}
The request does not include X-Bz-Server-Side-Encryption. The response still reports SSE-B2 with AES256 because it is now the effective default.
Using the S3-Compatible API?
Requests that omit encryption headers receive SSE-B2 automatically, reported through the S3-compatible AES256 value. PutObject, CopyObject, and multipart uploads all use the new default for the destination object. Valid SSE-C headers still take precedence.
Using the B2 Native API?
You can continue to omit SSE-B2 fields and headers. New uploads, large-file uploads, and destination copies use SSE-B2 by default. Applications can still explicitly request SSE-B2, but doing so is no longer necessary to receive encryption at rest.
Using an SDK, CLI, Integration, or the Web Console?
Because the protection is applied by B2, tools that already upload to Backblaze B2 benefit automatically. No special encryption flag, SDK upgrade, CLI update, or integration change is required. The Backblaze web consoles will show SSE-B2 or AES256 as the effective bucket default and continue to display the encryption actually used for each object.
SSE-C Is Still Available
Some organizations need direct control over the key used for a particular object. SSE-C continues to support that workflow. When a request includes valid SSE-C headers, Backblaze uses the customer-provided AES-256 key instead of SSE-B2 for that object.
As before, Backblaze does not retain the customer key. Customers using SSE-C are responsible for protecting and retaining their keys; a lost key cannot be recovered by Backblaze. You can also continue to encrypt data on the client side before uploading it. SSE-KMS is not part of this update.
What About Objects Already Stored in B2?
Always-on encryption is not retroactive. Objects already stored in a bucket keep the encryption state they had when they were written. We are not rewriting customer data in the background or changing the encryption metadata of historical objects.
If you want an older unencrypted object to use SSE-B2, upload it again or create a new destination copy. The new object is encrypted using the always-on default. Object-information and download responses continue to describe the encryption actually used for each object.
Why Always-On Encryption Matters
Encryption at rest is a foundational part of modern data protection. Making it automatic helps teams establish a consistent security baseline without adding another deployment step or relying on every application to make the same configuration choice.
It also keeps the developer experience simple. Teams can focus on moving, protecting, and using their data while Backblaze applies the default protection behind the scenes—with no added encryption charge or performance trade-off. That’s the kind of cloud storage experience we want to deliver: secure by design, straightforward to operate, and compatible with the tools customers already use.
Frequently Asked Questions
Do I need to change my application?
No. Applications that omit encryption settings automatically receive SSE-B2 for new uploads and destination copies. Existing request formats remain valid.
Can I disable server-side encryption for new uploads?
No. SSE-B2 is the effective default when SSE-C is not requested. Clearing or deleting an explicit bucket encryption configuration does not create an unencrypted default.
Does this encrypt objects that are already stored?
No. Existing objects retain their original encryption state. Uploading or copying an object again creates a new object that uses the always-on default.
Can I still use my own encryption key?
Yes. Supply the required SSE-C headers when you upload, copy, or access an SSE-C object. SSE-C takes precedence over the SSE-B2 default for that object.
Does always-on encryption cost more or affect performance?
No. SSE-B2 is applied at no additional charge and has no impact on upload or download performance. Normal Backblaze B2 storage and API charges still apply.
Available Starting September 14, 2026
Always-on SSE-B2 is available on September 14, 2026 for new buckets in every Backblaze B2 region. Existing buckets will be enabled gradually. For most customers, there’s nothing to turn on and nothing to migrate: once the default is enabled for a bucket, every new upload and destination copy receives SSE-B2 automatically unless you explicitly request SSE-C.
At NVIDIA’s GTC conference, Adobe’s CTO Ely Greenfield walked the audience through the company’s three-year journey building frontier generative AI models from scratch. And the AI training data pipeline required to keep thousands of GPUs productive.
Along the way, he showed a profiler readout from their early training runs—a visualization of exactly how much time each GPU was spending on actual computation versus sitting idle. It revealed that roughly two-thirds of GPU time was spent simply waiting for data. And that idle time had a price tag.
“If we were putting a million dollars into training,” he told the room, “that was $600,000 we were burning away on GPUs sitting and doing nothing.” In other words, roughly sixty cents of every dollar spent on GPU compute was being wasted.
Greenfield’s team traced the waste to two culprits, neither of which is unique to Adobe: whether data can reach your GPUs fast enough, and whether the work it represents is distributed evenly once it arrives.
One culprit is a storage problem. The other isn’t, but you won’t be able to fix it until you’ve solved the first one.
Culprit #1: Storage and retrieval speed
Adobe’s training data lived in petabytes of distributed cloud storage and had to be shipped out to thousands of GPUs constantly, over standard Ethernet. The dataset itself was enormous and varied—images and video, low-res and high-res, simple formats and expensive codecs, all moving at once. Standard networking, which was built for retrieving individual files on request, wasn’t designed for that kind of sustained, parallel, petabyte-scale movement. It became a massive bottleneck.
Checkpointing compounded the problem. As a safeguard, the training run would periodically write a complete copy of the model back to storage. Most of those checkpoints were never needed again. But writing and reading them still consumed real GPU time, which cost a lot of money whether they were used or not.
How Adobe fixed it
Adobe’s solution had two parts.
First, they replaced standard Ethernet with a high-performance networking fabric designed for the petabyte-scale traffic distributed AI training generates. Now, data could finally move at the pace their GPUs needed.
Second, they changed how they saved checkpoints. Instead of writing one giant file containing the entire model, they began breaking the model into smaller pieces and saving pipeline fragments to many places at once. Saving and loading checkpoints now takes significantly less time than it used to. If a checkpoint ever needs to be reassembled, that’s slightly slower, but it’s a rare event. The savings on every other write happen continuously, across thousands of GPUs, around the clock.
The underlying lesson is that for model training, parallel access and sustained high throughput are baseline requirements. Training data has to be immediately accessible at the pace your GPUs consume it, not tucked away in a storage tier that takes minutes or hours to retrieve.
Culprit #2: The data loader problem
A balanced data loader can only do its job if the data it’s balancing is actually available the moment it’s needed. That makes fast storage a precondition for everything else in the pipeline. But even after fixing the storage and retrieval speed culprit, Adobe still had a problem: the way training data was divided across the cluster meant some GPUs were doing far more work than others.
Their pipeline used a straightforward data-parallelism approach: slice the training data into equal-sized chunks and assign one chunk to each GPU in the cluster. But equal-sized chunks weren’t equal work. Some GPUs got simple, low-resolution assets that processed in seconds; others got large, complex files that took minutes. The fast GPUs finished early and sat idle waiting for the slow ones to catch up. And then all of them waited again while their results were merged into one updated model before the next round could begin.
How Adobe fixed it
Adobe stopped treating all data as equivalent. They custom-built a balanced data loader that understood the processing cost of each asset and distributed work so every GPU finished at roughly the same time. Then they restructured how computation was divided across the cluster to make the merging step dramatically cheaper.
A perfectly balanced data loader still idles if the data it’s waiting on hasn’t arrived yet. This is why storage can’t be an afterthought. The loader optimizes what happens once data is there, but storage determines whether it’s there at all.
And building something like Adobe’s balanced data loader takes real engineering investment, including time spent profiling workloads, testing distribution strategies, and tuning until every GPU finishes at roughly the same pace. Teams still fighting storage bottlenecks rarely get to that work. Their engineers are busy figuring out why GPUs are idle in the first place, not optimizing how work gets distributed once data arrives. Removing the storage bottleneck frees up the engineering time needed to tackle the data loader problem properly.
From 40 to 80 cents
After addressing both culprits, Adobe’s GPUs ran at roughly 80% utilization. After accounting for the coordination overhead inherent to running thousands of machines together, 80% is close to the practical ceiling. That’s the difference between a GPU cluster that’s mostly waiting and one that’s mostly working.
The Storage Side of the Solution
Backblaze B2 Overdrive addresses the storage side of exactly the problem Adobe ran into. B2 is always-hot object storage, with no tiering, no retrieval delays, and no waiting for data to be promoted from a cold tier before training can begin. Training data stays immediately accessible whether it was written an hour ago or six months ago.
But availability alone isn’t enough if data can’t move fast enough to keep up with the cluster. B2 Overdrive adds the throughput layer: at up to 1Tbps, it’s designed to keep petabyte-scale GPU clusters fed continuously, not just handle occasional bursts of traffic. Both layers are S3-compatible, so they drop into existing PyTorch or TensorFlow pipelines without a rewrite. And because egress is free, moving training data between storage and GPU compute—across regions or providers—doesn’t add a cost penalty on top of a performance one.
Checkpointing benefits from the same foundation. Adobe’s solution of breaking the model into fragments and saving them to many places at once only works if the underlying storage is fast and parallel enough to make it pay off. Always-hot, high-throughput storage makes checkpoint writes and recoveries faster across the board, so they cost less GPU time whether they happen rarely or often.
Backblaze can’t write your data loader for you, but it can make sure that once you’ve built one, it isn’t waiting on storage to do its job.
If you’re running a Mac fleet, Jamf is often where everything starts. It handles provisioning, policies, app installs——the orchestration that keeps your fleet sane. But backup is the thing that doesn’t fit. Jamf gives you control over every Mac, but it doesn’t protect the data on them. Backblaze closes that gap without changing how your team works.
Webinar: Building a Complete Mac Protection Strategy
Join Solution Engineers from Jamf and Backblaze for a practical discussion on building a complete Mac protection strategy.
The device ownership problem
Either you know who owns every device upfront (rare), or you don’t (common). Most teams end up doing some mix: devices that came pre-assigned, devices still waiting for user mapping, devices that migrated between teams. You write a script to fix it, then another to catch the next variation. Three months later, you’re not sure if every device is actually backed up or just supposed to be.
The new solution: Two ways to match devices to users. Pick the one that matches your reality.
This update solves the core friction: you don’t have to choose one deployment model anymore.
Method 1: Fixed email (for controlled environments) If you already know who owns each device at install time, for example, if you have clean HR data synced to Jamf, you can pass the user email directly during deployment. The installer uses it to set up the account automatically. No guessing, no drift.
Method 2: Dynamic user detection (for real-world environments) If you don’t have clean data upfront (e.g. when new devices arrive, get imaged, and wait for assignment) the installer waits until a user logs in. Once a user signs in, Backblaze can automatically associate the device with the appropriate user account based on the deployment configuration and identity information available on the device. This reduces the need for manual user assignment and helps prevent devices from being left unprotected.
Or mix them: some devices get email, others get dynamic detection. The system can now handle both in the same deployment.
What this means for your workflow
You push the Backblaze installer through a Jamf policy, same as any other app. Set your preferred method (fixed or dynamic) once at the group level, then let it run. Devices show up in the Backblaze console under the right user, with the right backup scope, no extra steps.
When something does need adjustment—a device moved teams, a user credential changed—you handle it the same way you’d handle any other Jamf-managed app. Script it, reconfigure it, whatever your existing process is. Backup can now follow the same deployment and management workflows your team already uses for other Jamf-managed applications.
Fewer things that can go wrong means less time managing edge cases
The friction point used to be this: you’d deploy backup, then spend the next week chasing down why a handful of devices aren’t appearing correctly. Someone’s account didn’t match. A device landed in the wrong group. Now you’re writing workarounds.
With two deployment methods that actually handle different scenarios instead of forcing everything into one model. The new deployment options reduce common onboarding issues that often require follow-up troubleshooting.Fewer edge cases means fewer scripts to maintain, fewer devices to manually fix, fewer things to check on at 3am.
It still runs the same way once it’s installed
Nothing else about Backblaze changes. It backs up user data automatically, without caps or limits. Pricing stays flat per device. Restore works the same way. This update is purely about getting it deployed cleanly—the actual backup part just keeps working.
How to start
Pick a small group of devices. Deploy through Jamf. Watch what happens for a week. You’ll see pretty quickly whether the user-matching is working and whether this fits your environment.
Building generative media applications on object storage: What the strongest projects have in common
Between June 22 and August 3, 2026, 1,314 people entered hundreds of projects into a single brief: build a generative media app on Backblaze B2 object storage, orchestrated through the open-source Genblaze SDK, for a share of a $10,000 prize pool.
Almost every entry could generate an image, a video, or a soundtrack, and generate it well. What separated the strongest was the layer underneath: what gets written down, what can be proved later, and what happens when a file has to be checked, corrected, or locked against deletion.
Here’s a closer look at the five that went furthest, and the parts worth reusing. Every entry is browsable in the hackathon project gallery.
The brief, and why it was narrow on purpose
The brief was narrower than most hackathons get. Submissions couldn’t just be a working demo and a repo. Devpost required teams to explain, in writing, how their app actually used both Backblaze B2 and Genblaze, and to list every provider and model behind it. Judging ran against four criteria: real-world utility, production readiness, meaningful use of B2, and meaningful use of Genblaze.
That last pair is the constraint that did the work. “Meaningful use” rules out the default architecture, where a team generates an asset, drops the bytes in a bucket, and calls that storage. It forces a decision about what the storage layer is actually for. What follows is written the way a technical and creative director would walk five finished pipelines against exactly that rubric: who each app is actually for, whether it holds up past the demo, and how deep the storage and orchestration choices go.
The two primitives
Backblaze B2 is the ground every one of these apps had to build on: S3-compatible object storage, sized for the sheer volume of generated assets, thumbnails, metadata, and provenance records a media pipeline throws off, free to start with 10GB included.
Genblaze, Backblaze’s open-source orchestration SDK, is what feeds it: a unified Pipeline API spanning providers like OpenAI, Google, Runway, Luma, ElevenLabs, and Stability Audio, plus models served through platforms such as GMI Cloud and NVIDIA NIM, so a team can swap providers without rewriting its orchestration. Every run produces a canonical provenance manifest that can be embedded directly into the media file itself (an .mp4, a .png, an .mp3) and persisted to B2 or any S3-compatible store.
The hackathon also partnered with GMI Cloud, giving teams easy access to open-source generative models for image, video, audio, chat, reasoning, and multimodal work, which is why it turns up as a provider more than once below.
Two primitives, six weeks, hundreds of teams, and five very different examples of rigor.
A review room for AI video ads that doesn’t make you wait for the whole render.
firstframe builds a review room for the marketing and creative teams who commission AI-generated video ads: instead of waiting on a full multi-scene render before anyone can react, it streams the first finished scene as a live HLS playlist the moment it’s ready, appending segments as later scenes land. A reviewer starts giving notes while the ad is still being made, not after.
Every generated scene is scored by an actual vision model before a human ever sees it, so obviously broken output gets caught and retried automatically rather than shipped to a reviewer’s inbox. A failover step swaps in a backup model only on a genuine provider error, never on an ordinary slow response, and once a scene clears review its master file and manifest are locked against deletion for thirty days: a guarantee the code proves by trying to delete a locked file and catching the rejection. Automated QA paired with a tamper-evident record of what was approved is what turns a generation pipeline into something a brand could actually sign off on.
On B2, the bucket’s folder structure doubles as a workflow: a scene moves through incoming, running, provenance, approved, and rejected prefixes as it clears review. Once a scene is approved, its master file and manifest get a real thirty-day write-once hold using B2’s Object Lock in Governance mode, and the code proves that isn’t just decorative by trying to delete a locked object by its version ID and catching the rejection B2 throws back. A reviewer’s application key is scoped to the readFiles capability with a name prefix restricting it to the approved folder alone. Four separate lifecycle rules cover the bucket’s different prefixes: stalled uploads in incoming have their multipart parts cancelled after 24 hours, while rejected, in-progress, and approved objects each age out on their own separate timers. The video segments themselves land in B2 as ffmpeg finishes each one, with the playlist rewritten after every segment, which makes B2 a live broadcast target rather than an archive that fills up after the fact. Reads go out as path-style presigned URLs, working around a known issue where virtual-host-style presigning fails on a private B2 bucket. B2’s own Event Notifications, five signed webhook rules, keep the review room in sync in real time, with a fallback to plain polling if an account’s Event Notifications API isn’t enabled. The app also watches B2’s own transaction cap and backs off to local disk instead of crashing when a call gets rejected for exceeding it.
On Genblaze, generation runs through an AgentLoop scored by a ThresholdEvaluator. The judge is a real vision model, an NVIDIA NIM llama-3.2-90b-vision-instruct instance grading the actual rendered keyframes, not a fixed retry count. Two pipeline branches, audio and video, fan into a single compositor node instead of running as a straight chain, a fallback_models failover is wired in and confirmed to trigger only on a genuine model error rather than a timeout, and every run carries two layers of lineage: a shared run id across scenes and loop iterations, plus a second, custom chain id layered on top of that. The team even embedded the manifest directly inside the delivered MP4, so a separate verification command can re-download and re-hash every asset the file claims exists. Along the way they filed three pull requests and an issue against Genblaze itself.
firstframe puts B2’s feature set to work in front of the reviewer. Object Lock in Governance mode, scoped application keys, lifecycle rules, Event Notifications, and presigned URLs are all load-bearing parts of the review workflow, doing visible work on every scene that moves through it. That’s architecture built to be trusted, not just to work.
A campaign generator built to double-check its own storage, re-verifying every asset the moment it’s read back.
beavous is built for the marketers and small commerce teams who need a full paid-social campaign out of a single product photo: not one hero image, but four creative concepts, sixteen cropped aspect ratios for every placement, on-label ad copy, and a portrait video reel, packaged as a verified ZIP pulled straight from B2.
A public API hands off to a private worker behind a task queue, and every campaign is namespaced to an organization so tenants stay isolated from each other. When a generation gets rejected, the app doesn’t start over. It chains a correction onto the original attempt, which is closer to how a real creative review actually works than a one-shot retry.
On B2, keys are organized hierarchically by organization and campaign rather than by content hash, because the product is multi-tenant by design. Every upload and download goes through a presigned URL, and the database never stores a raw link, only an object key and a hash. Every time an asset is read back, beavous re-downloads it and re-hashes the bytes independently, rather than trusting a manifest check alone. B2 is treated as the single, sole system of record for every generated asset: a clean, one-source-of-truth design with nothing else to keep in sync.
On Genblaze, three custom providers handle Gemini image generation, Gemini video, and Veo image-to-video, each with its own tiered pricing registered on the model. The more interesting move is a correction chain: when a generation gets rejected, its manifest becomes the parent of the next attempt, an explicit correction lineage most one-shot generation pipelines skip entirely. Prompts are marked private so the text never lands in the public manifest, only a hashed reference to it does, and before any manifest is trusted as a correction parent it gets independently re-verified, not assumed correct just because it was the app’s own write.
beavous’s answer to “do you trust your own storage” is simple: no, never. Check it again, every time. That’s a slower design than trusting your own write, and a more honest one.
A build system for generative media that can prove its own reuse, recovery, and release integrity, live, against B2.
takegraph is built for teams running a production, not a single generation: the kind of project where a script tweak halfway through shouldn’t mean re-rendering everything from scratch. It treats the whole thing like a software build: a content-addressed dependency graph that, when a spec changes, recomputes fingerprints, rebuilds only what’s actually invalidated, and reuses everything else.
A team can also re-download and re-hash the actual bytes behind any reuse, recovery, or release straight from B2, live, checking integrity themselves instead of trusting a log. That kind of self-auditing separates a pipeline meant to run unattended for months from one built to survive a single demo.
On B2, content-addressed keys use a two-level hash split so directory listings stay fast at scale, B2’s own Event Notifications (HMAC-SHA256-signed webhooks) feed a background process, and a separate reconciler periodically re-checks everything by hand in case a webhook is ever missed, coordinated across workers with a database lock so only one reconciler runs at a time. Unvalidated uploads land in a quarantine prefix backed by a real lifecycle rule that expires it automatically, and a bad key gets rejected outright rather than silently rewritten. Two least-privilege application keys, one for day-to-day work and one for releases, are each scoped to a single bucket, and CORS rules on the work bucket exist specifically to support presigned browser uploads. Verification (re-download, re-hash, prove it) is a feature of the product, not an internal tool.
On Genblaze, takegraph builds a real pipeline around the idea: a dedicated run builder, a content-addressable storage sink, manifests, and observability events tied to every step. The team kept its media-generation side lean, calling straight through the GMI Cloud connector for image and video (one of the hackathon’s partner platforms), and pointed all of its custom engineering at the layer that makes the whole pitch work: the storage and consistency system underneath.
takegraph turns storage verification into the product itself: reuse, recovery, and release integrity are things a user can ask the system to prove, live, rather than take on faith. That’s B2 treated as a system of record in the fullest sense: self-healing, event-driven, and built to survive a missed webhook without anyone noticing.
A comic studio with a provider for every model it needed, and a manifest for every frame it drew.
Ninth is built for indie comic authors and motion-comic creators working on a small budget, who revise a scene a dozen times before it’s right and can’t afford to pay for a fresh generation on every pass. Describe a story, and it writes, draws, casts, and stages it panel by panel on an editable timeline, then bakes the result to an MP4.
An edit doesn’t force a re-generation: assets are pulled from a semantic library whenever something close enough already exists, and everything the AI produces (timing, layer position, camera, bubble placement, even the artwork itself) stays editable in place afterward. That reuse-first design is backed by 126 regression tests and a render path that shares its engine with the live editor, so what a creator previews is exactly what gets exported.
Its B2 layer favors verified durability: flat content-addressed keys and a manifest per run, plus real, working endpoints for audit, restore, and backfill that report exactly what’s on B2 versus what’s only on local disk, and rebuild the difference with a SHA-256 check on every recovered file.
On Genblaze, Ninth wrote seven or eight custom providers, covering nearly every model it reached for: Azure’s image model, Gemini’s aspect ratios, Veo keyframes, Gemini’s video interpolation model, ElevenLabs music, and two separate structured-text providers. Each one exists for the same reason: to keep that artifact inside a pipeline and give it a manifest, so a generated frame always carries a record of the run and the prompt that made it.
Ninth’s mention is for discipline: the project that took “every generated frame should be reproducible and recoverable” most literally, and built the tooling to prove it on demand.
A spatial twin that gives a person’s spoken correction the same provenance as a model’s output.
Spatialize is built for venue and accessibility teams who need to rehearse a step-free route through a space before anyone sets foot in it: it turns a flat floor plan into a voice-navigable spatial twin, extracting validated 3D geometry from the plan image, then answering spoken questions with route guidance grounded in that geometry.
Because the underlying use case is safety-adjacent, nothing the model proposes is trusted outright. Every extracted floor plan, and every voice-driven edit to it, has to pass the same deterministic geometry validator before it’s accepted, so a plausible-looking but wrong route never quietly makes it into a rehearsal. When that validator rejects an attempt, it hands back the exact error, and the next attempt corrects specifically that, not a blind retry.
On B2, Spatialize favors resilience: every read goes through a short-lived, presigned link, and if B2 isn’t configured at all, the app quietly falls back to a local, path-safe store instead of failing to boot. It runs two storage paths side by side (its own hierarchical object store for run and scene state, and a separate Genblaze storage sink dedicated to generated-media provenance), keeping application state and generation history cleanly apart.
Under the hood, an agentic loop drives the floor-plan extraction, evaluated at each attempt by that same deterministic validator rather than an LLM’s opinion. Three custom text-to-speech providers form a genuine fallback ladder: a cloud model first, a lightweight third-party API next, and a self-hosted, zero-credential model as the last resort, so a narration request degrades gracefully rather than failing outright. The standout idea: a voice-driven edit to the scene creates a new version tagged as a human change, with the actual transcript kept as evidence, so every point in the final scene traces back to either a model’s manifest or a person’s own words.
Spatialize’s real achievement is conceptual: it gives a spoken correction the same seriousness as a model’s output, tracing every point in the final scene back to either a manifest or a transcript. That’s provenance thinking applied somewhere most generative pipelines never point it.
Same brief, different rigor
Every winning project found its own discipline. What they share is how many different, equally valid kinds of rigor a small team can bring to the same two primitives in six weeks. firstframe made B2’s write-once guarantee visible to a reviewer in real time. beavous made re-verification a habit instead of an afterthought. takegraph made its storage layer heal itself. Ninth made every one of its seven custom providers answerable to the same manifest. Spatialize made a human correction as provable as a model’s.
None of that shows up until a team stops treating storage and orchestration as plumbing and starts treating them as part of the design. firstframe’s win sits at the intersection of both: the same rigor that scores a generated frame with a vision model also locks the finished one against deletion.
What you can build on
Strip the five projects back and the same handful of moves keep appearing, none of which need a hackathon, a large team, or a novel model:
Object Lock in Governance mode turns “approved” from a database flag into a storage-level fact, and firstframe proves the hold is real by attempting the delete by version ID and catching the rejection B2 returns.
Bucket prefixes (incoming, running, approved, rejected) give you queue semantics without a queue, with a separate lifecycle rule per prefix so stalled multipart uploads and dead rejects expire on their own timers.
Re-download and re-hash on read, the way beavous does, because a non-deterministic pipeline produces a lot of near-identical artifacts and hashing is how you know which one you’re holding.
Event Notifications as the fast path, a periodic reconciler as the source of truth, so a dropped webhook costs you latency instead of correctness.
Content-addressed keys with a two-level hash split keep directory listings fast at scale and make reuse cheap: same fingerprint, same bytes, no second generation to pay for.
Application keys scoped one per role, like a reviewer key limited to the readFiles capability with a name prefix restricting it to the approved folder.
Correction lineage instead of retries: the rejected run’s manifest becomes the parent of the next attempt and carries the specific error forward. beavous and Spatialize arrived at this independently, which suggests it’s the general shape rather than a niche trick.
All of it is available today. B2 starts free with 10GB, and Object Lock, lifecycle rules, Event Notifications, scoped application keys, and presigned URLs are in the API from day one. Genblaze gives you one Pipeline API across OpenAI, Google, Runway, Luma, ElevenLabs, and Stability Audio, plus models served through GMI Cloud and NVIDIA NIM, and a canonical provenance manifest out of every run that embeds straight into the .mp4, .png, or .mp3 you ship.
A good first project is smaller than any of these five. Take a pipeline you already have, write a manifest for every run, persist it to B2, and add one endpoint that re-downloads and re-hashes an asset to prove the manifest is honest. That’s a weekend of work, and everything above is a variation on it. Genblaze is open source, and three of the pull requests behind firstframe are already in it.
For more ideas, the full project gallery has every entry from the hackathon, and there’s a lot in there beyond the five covered here.
Since April 2013, Backblaze has published the daily health readings of every hard drive running in our data centers. Model, serial number, failure flag, and dozens of Self-Monitoring, Analysis, and Reporting Technology (SMART) attributes, collected into a CSV for each day, released publicly every quarter, for free. We built Drive Stats as a mechanism to understand our own fleet, then published almost on a whim—so much so that the original idea is credited to two Brians. What happened next was an exciting surprise.
More than 227 papers and articles have cited Drive Stats as a primary dataset since 2018. Researchers have trained transformer architectures, long short-term memory (LSTM) networks, survival models, and gradient-boosted ensembles on it. The dataset that started as an internal reliability tool has become one of the most-cited open benchmarks in hard drive failure prediction research.
What makes Drive Stats so valuable?
Drive Stats reflects a live, continuously operating commercial fleet of drives: different manufacturers, different models, different capacities, all spinning in production Storage Pods under real workload conditions. That combination of scale and heterogeneity is rare, and it is exactly what makes the dataset especially useful to researchers.
For storage engineers and data scientists, the dataset checks every important box: real-world origin, a long time horizon, labeled failures, an open license, and an active maintainer that publishes new data each quarter. Here are a few other specifics worth understanding before diving into the research:
Download access: The full quarterly archive is available for free on the Backblaze Drive Stats page under the MIT License.
Open license: Backblaze asks three things of anyone who uses the data: that they cite Backblaze as the source, they accept responsibility for how the data is used, and they do not resell it.
SMART attributes: Each daily snapshot includes raw and normalized values for more than 70 different SMART attributes per drive. We define a drive failure in our dataset based on a few metrics, which we talk about in previousreports, as well as articles dedicated to parsing the program.
Scope and coverage: We began publishing quarterly hard drive data in 2013. The current dataset spans more than a decade of operation and covers hundreds of thousands of individual drives across manufacturers including Seagate, HGST, Western Digital, and Toshiba. Each year, we also compile data related to annualized failure rates (AFR) and lifetime failure rates across all manufacturers. Lifetime failure rates indicate the probability that a drive will fail over the course of its lifetime, while AFR indicates the probability a drive will fail during a year of operation. Rates are expressed as a percentage. Data related to lifetime failure excludes drive manufacturers with less than 500 units deployed, and all drives must have 100,000 active drive days to be included in the lifetime data set. The 2025 annual report recorded an annualized failure rate (AFR) of 1.36% across the fleet, down slightly from 1.57% in 2024, reflecting multiple factors (average drive age, technology improvements, drive size increases, cost per gigabyte, and market demand).
Most importantly: the economics of drives, and the measures people take to keep them spinning within a data center, are fundamentally different than in a consumer use case. In some ways, it’s the perfect test—the drives are always on, and we run them until they give up the ghost. In others, it’s a bit deceptive—most people don’t have alerts set up to monitor drive health in their home environments.
Of course, many do. Data is important, and for those who schedule weekly maintenance for your home networks: we love it, we’re here for it, and us too.
Academic research built on Drive Stats
The papers below represent a cross-section of research that uses Drive Stats as a primary dataset. Each represents a meaningfully different approach to the same core problem: predicting when a hard drive will fail, with enough lead time to act on it.
TFBEST: Dual-Aspect Transformer With Learnable Positional Encoding for Failure Prediction
Experiments on Seagate hard disk drive (HDD) data led the authors to propose a novel transformer architecture for predicting failures in hard drives that significantly outperformed prior state-of-the-art remaining useful life methods on the Drive Stats benchmark.
Their proposed architecture—the Temporal-Fusion Bi-Encoder Self-attention Transformer—is an encoder-decoder model trained on the full 10-year Drive Stats corpus (from 2013 to the time of article). Rather than classifying drives as failed or healthy within a fixed horizon, TFBEST predicts a sequence of days-to-failure, giving operators a window, rather than a binary alarm. The paper also introduces a confidence-margin statistic that manufacturers can use to set replacement thresholds with quantified uncertainty.
Large-Scale End-of-Life Prediction of Hard Disks in Distributed Datacenters
The authors presented a long short-term memory (LSTM) model that used understanding gleaned from Drive Stats to aid in predicting an output sequence of the number of days remaining before the possible failure of a disk. The LSTM posted a root mean square error of 0.83 during training, and 0.86 during testing across the full 10-year corpus, and generalized competitively across multiple Seagate model families.
The core architecture was an encoder-decoder LSTM network: the encoder processed a window of historical SMART readings for a given drive; the decoder produced a multistep output sequence representing the predicted days-to-failure. The model was trained and validated on all Drive Stats data available at the time, roughly 35GB, covering Seagate drive models with significant failure populations.
Leveraging Survival Analysis in Cost-Aware Deepnet for Efficient Hard Drive Failure Prediction
To address the significant imbalance of real-world datasets used for drive-failure detection—the relatively small number of failures when compared to the number of drives operating normally—the authors relied on the SMART attributes found in Drive Stats to uncover new insights into drive health and failure.
They used a dual-track approach: a deep-learning track for failure prediction and a survival-analysis track for identifying which attributes most strongly govern time-to-failure. Together, the two tracks provided both operational predictions and mechanistic insights useful for data-center management strategy.
Examining the Impact of Critical Attributes on Hard Drive Failure Times: Multi-State Models for Left-Truncated and Right-Censored Semi-Competing Risks Data
Authors: Jordan L. Oakley, Matthew Forshaw, Pete Philipson, Kevin J. Wilson
Many hard-drive failure prediction papers ask a binary question: Will this drive fail in the next N days? This paper asked a more nuanced statistical question: How do intermediate critical states defined by deteriorating SMART attributes affect the time distribution of eventual failure?
Oakley and colleagues first defined critical attributes and critical states using Drive Stats SMART readings, and then fit multistate survival models to the resulting semicompeting risks structure. These risks arise because a drive can move from healthy to critical (nonterminal) before failing (terminal), but failure can also occur without a detectable prior critical state. The multistate framework handled both pathways in a single coherent model.
The key contribution was a set of dynamic predictions of conditional survival probability that updated as the observed state of a drive changed – so operators got a live risk estimate, not a static score. Experiments on Drive Stats data confirmed that drives entering critical states are substantially more likely to fail.
AI/ML Models and Projects Built on Drive Stats
Academic papers are one signal that a dataset has earned its place in a field. Practitioners building things with it are another. A growing body of work, including open-source projects on platforms like GitHub, helps translate academic research into practical, runnable code, and provides additional confirmation of Drive Stats as a standard benchmark for the field.
The project aimed to create a binary classification model using machine-learning algorithms to predict the probability of drive failures based on SMART data, along with other features such as brand and storage capacity. It applied three methods: random forest, XGBoost, and a combined ensemble to Drive Stats SMART attribute data.
Large-Scale End-of-Life Prediction of Hard Disks in Distributed Datacenters
For practitioners building their own Drive Stats pipelines, this is one of the few public examples that addresses the full stack data ingestion, feature engineering, class imbalance, and sequence modeling, rather than demonstrating a model on a precleaned subset. Its combination of XGBoost for feature selection and LSTM for sequence prediction serves as a practical template for anyone working with raw quarterly CSV files.
Beyond the model architecture described in the academic paper section above, this project is notable for its engineering approach to handling Drive Stats at scale. The team built a preprocessing pipeline using PostgreSQL to ingest, filter, and join the quarterly files; used XGBoost across the full SMART attribute set; and applied interpolation to fill gaps, before feeding sequences to the encoder-decoder LSTM.
Are There Manufacturer Differences in Hard-Drive Reliability?
Contributor: Christoph Siemroth, Yeomyung Park
Venue: IEEE Transactions on Cloud Computing
Researchers used Backblaze’s large data-center dataset to compare failure rates across four manufacturers (HGST, Seagate, Toshiba, and Western Digital). Duration regression models controlled for drive age, capacity, and form-factor, and the findings concluded that HGST drives fail least often (about 42% of Seagate’s failure rate. However, WD drives outperformed Seagate but fared worse than HGST. Toshiba’s failure rate is similar to Seagate’s.
The study revealed a significant reliability gap between HGST and Seagate, doubling the financial burden for large-scale operators related to replacement-related labor and other costs. Drive failure analytics highlighted in the study can be used by large-scale operators to forecast future costs, informing procurement decisions.
Drive Stats research at a glance
Paper / Project
Authors
Venue / Platform
What It Predicted / Built
TFBEST: Dual-Aspect Transformer With Learnable Positional Encoding for Failure Prediction
Mohapatra, Sengupta
arXiv (2309.02641)
A novel, high-performing transformer architecture for predicting hard-drive failures
Large-Scale End-of-Life Prediction of Hard Disks in Distributed Datacenters
Mohapatra, Coursey, Sengupta
IEEE
An LSTM helps to predict the number of days to a given disk’s failure to a high accuracy level
Leveraging Survival Analysis in Cost-Aware Deepnet for Efficient Hard Drive Failure Prediction
Ahmed, Green II
Neural Computing and Applications, Vol. 37
Operational predictions and mechanistic insights for data-center management strategy
Examining the Impact of Critical Attributes on Hard Drive Failure Times
Oakley, Forshaw, Philipson, Wilson
Applied Stochastic Models in Business and Industry, Vol. 40, Issue 3
Confirmation that drives entering critical states defined by deteriorating SMART attributes are substantially more likely to fail
HDD Failure Prediction Using Machine Learning
warc0s
GitHub
A binary classification model using machine-learning algorithms to predict the probability of drive failures
Large-Scale End-of-Life Prediction of Hard Disks in Distributed Datacenters
rohanmohapatra
GitHub
A practical template for practitioners working with raw quarterly CSV files to build their own prediction pipelines
Are There Manufacturer Differences in Hard-Drive Reliability?
Siemroth, Christoph Park, Yeomyung
IEEE
A comparison of hard-drive reliability across four manufacturers, using data regression models.
The case for open data
The breadth of research is a direct result of open datasets. These citations occur because the data was consistently available every quarter for more than a decade—and it helps that we built a community of similarly interested people, too.
For research communities, open datasets function the way open-source libraries do: they create a shared foundation that everyone can build on and compare against. Drive Stats has earned that role in hard drive failure prediction by showing up reliably for over 13 years. A few things make open data particularly useful:
Ecosystem reach. Drive Stats doesn’t exist in isolation: We publish it on Hugging Face, where it sits alongside hundreds of thousands of open datasets, across domains from natural language processing to genomics. Kaggle hosts it alongside tens of thousands of community notebooks and kernels.
Reproducibility. Drive Stats is public, permanently archived, and available for download. A paper published today cannot recreate historical data. There’s not really a corollary in a field where most real-world fleet data is proprietary and inaccessible—but we’d love people to join us.
Research velocity. When data is freely available, there’s no need to spend months negotiating access agreements. You simply download Drive Stats, read the schema documentation, and start building. The papers mentioned in this article collectively span transformer architectures, survival models, deep neural networks, and gradient boosting, all on the same dataset. You can’t necessarily call it a direct comparison, but it does make one thing clear: hardware is central to the cloud conversation.
Sign up for the Drive Stats newsletter
The same data that powers academic research also powers our own reliability reporting: The annualized failure rates, SMART attribute analysis, and transparency have made Drive Stats a standard in the field for more than a decade. And that data keeps coming, with a new release every quarter, since 2013.
If you’re working on failure prediction, predictive maintenance, or just want a real-world labeled dataset for benchmarking, this is the one researchers keep reaching for.
Backblaze Drive Stats is a publicly available dataset of daily hard drive health snapshots from our data centers. Published quarterly since 2013, it includes Self-Monitoring, Analysis, and Reporting Technology (SMART) attribute readings; failure labels; and model information for hundreds of thousands of drives. The data is free to download from the Backblaze Drive Stats page.
Has Drive Stats been used in academic research?
Yes. More than 227 papers and articles have cited Drive Stats as a source since 2018. Researchers have used it to develop and test hard drive failure prediction models, survival analysis frameworks, and deep learning architectures across venues including IEEE, Springer, Wiley, and arXiv.
Which AI/ML models were trained on the Backblaze dataset?
Researchers have trained a wide range of models on Drive Stats data, including long short-term memory networks, transformer architectures, 1D convolutional neural networks, gradient-boosted trees, survival analysis models, and ensemble methods.
Is the Backblaze Drive Stats dataset on Hugging Face?
We publish Drive Stats on Hugging Face at huggingface.co/datasets/backblaze/Drive_Stats. The repository contains over 388 million records and grows by more than 240,000 records per day. It is append-only, meaning daily snapshots are never updated or deleted once written, making it particularly useful for reproducible research.
Why do researchers use open hard drive datasets?
Open datasets like Drive Stats allow researchers to benchmark models against consistent real-world data, reproduce published results, and build on prior work without access to proprietary fleet data. Because Drive Stats reflects a heterogeneous, production-scale environment rather than a lab setting, it provides a uniquely credible benchmark for evaluating failure prediction methods.
How many times has Drive Stats been cited in research?
More than 227 papers and articles have cited Drive Stats since 2018. The actual number continues to grow as researchers publish new work on hard drive reliability, predictive maintenance, and artificial intelligence/machine learning (AI/ML) model benchmarking.
At GTC this year, Jensen Huang put a number on a problem that most enterprise AI teams already feel but struggle to articulate: about 90% of what gets generated every year is unstructured data. This includes PDFs, emails, video, contracts, support tickets, and voice recordings.
Until recently, that data was, in his words, almost entirely useless. You could store it or search it by keyword, but machines couldn’t read it, understand what it meant, or draw any connections between it and other content.
GenAI has changed that. RAG pipelines, vector databases, and embedding workflows give machines a way to process unstructured content, comprehend its meaning, and synthesize information across the entire enterprise.
The problem is that these tools put a completely different set of demands on storage than anything that came before them. And most enterprise storage wasn’t built for it.
The access pattern no one planned for
Traditional enterprise storage assumes that data gets written and then occasionally retrieved. The architecture for it was built with hierarchical file systems and tiered storage (hot archives for data that gets accessed regularly, cold archives for anything that hasn’t been touched in a while). It worked well for decades, until RAG pipelines broke it.
A RAG pipeline works by reading your documents and converting them into a format the AI can search. But that conversion process is not a one-time event. It has to be run repeatedly as you test, adjust, and update. Every adjustment means re-reading the same content, re-processing it, and re-writing the results back to storage.
For example, the pipeline breaks documents into chunks because the AI can only search effectively when content is divided into manageable pieces. The size of those chunks directly affects how well the AI answers questions. Too large, and the AI retrieves too much irrelevant content. Too small, and it loses context.
Whenever you have to update your underlying documents, the pipeline has to re-read and re-process everything affected by the change. The same is true when upgrading to a newer AI model, because the new model produces different representations of the same content and requires everything to be re-converted.
While the pipeline is reading, it’s also saving converted content, updated search indices, and checkpoints. And what it saves is tiny. Embeddings, vector chunks, and metadata objects are often just a few kilobytes each, but a production RAG pipeline generates millions of them. Legacy storage treats every save operation the same regardless of file size, so saving a million tiny files costs nearly as much as saving a million large ones.
Tiered storage exacerbates this even more. These systems judge which data is still needed and which can be moved to cheaper, slower storage based on how recently something was accessed. But a RAG pipeline might go quiet for weeks between runs and then suddenly need everything at once. Or it might re-index documents on a schedule that the storage system doesn’t recognize as regular access. Either way, the tiered system sees cold data and moves it to a slower tier. When the pipeline needs that data back, it waits and pays a retrieval fee before it can proceed. That cost and delay compounds across millions of objects and dozens of pipeline runs.
The governance problem hiding inside your index
When a RAG pipeline indexes documents into a vector database, it takes a snapshot of your data at that moment in time. The embeddings it generates reflect the content of those documents as they existed when the pipeline ran. When the original documents are updated or changed, the snapshot doesn’t change with them. The vector index keeps pointing to the old version, and the AI keeps retrieving it and presenting it as current fact.
To a user, that looks like hallucination. The model is confidently citing a document that no longer says what the model thinks it says. But the failure isn’t happening inside the model; it’s happening at the storage layer. Specifically, in the gap between when source documents change and when the index gets updated.
Most enterprises running RAG pipelines today have no systematic way to close that gap. Document management systems aren’t built to notify downstream AI pipelines when content changes. Vector databases aren’t built to automatically invalidate and re-index affected embeddings. The result is an AI system that’s architecturally incapable of knowing when its knowledge has gone stale, so it presents outdated information with the same confidence as current information.
What GenAI storage actually requires
Closing the gap between what RAG pipelines demand and what legacy storage delivers requires three things:
Sustained high throughput. RAG pipelines generate continuous, mixed traffic at every stage of the process—ingesting documents, processing them, writing the results to an index, and querying that index—often all running simultaneously. Storage must be able to move data in and out fast enough to match the speed at which the pipeline generates requests, and sustain that speed across the entire duration of a run, not just handle short bursts.
Always-hot architecture with no tiering. Every document needs to be immediately accessible regardless of when it was last touched. This is not just for pipeline performance, but also because slow re-indexing is what produces stale outputs. When source documents change, the pipeline needs to re-index immediately. Storage that puts documents behind retrieval delays or tiering penalties widens the window in which the AI is working from outdated information and presenting it as fact.
Free data movement. RAG workflows span multiple GPU providers, MLOps platforms, and inference environments across multiple regions. Storage that charges egress fees for every transfer turns architecture decisions into cost calculations and discourages the experimentation that gets AI systems from prototype to production.
The storage layer that doesn’t get in the way
Backblaze B2 Overdrive is built around exactly these requirements. It is always-hot object storage with no tiering, no retrieval delays, and no waiting for data to be promoted before a pipeline can run. Every document is always available, regardless of how recently it was written, which means when the pipeline needs to re-index, storage never slows it down.
At up to 1Tbps sustained throughput, it keeps high-volume RAG pipelines fed continuously through the constant mixed traffic of reads and writes they generate. Because egress is free, teams can move data between storage and compute across regions and providers without a cost penalty. And S3 compatibility lets B2 Overdrive drop into existing LangChain, LlamaIndex, and vector database pipelines without rewrites.
Ninety percent of enterprise data is sitting in formats that, until recently, machines couldn’t do anything useful with. The tools to unlock it now exist. How well they perform and what they cost to run depends largely on the storage underneath them.
Organizations rarely struggle with a lack of storage options. More often, they struggle with determining which solution best fits the way their data is created, accessed, and protected: backup versus cloud storage.
That’s especially true when evaluating backup and cloud storage solutions.
The terms are often used interchangeably, but backup and cloud storage are designed to solve different problems. Understanding those differences can help you build a more effective data protection strategy—whether you’re protecting a personal laptop, a growing media archive, employee endpoints, or critical business data.
At Backblaze, Computer Backup and B2 Cloud Storage serve distinct purposes. For some customers, one solution is the clear choice. For others, the strongest approach combines both.
Before comparing features, it’s helpful to start with a few foundational questions.
The answers often reveal whether you’re primarily trying to protect a computer, store data in the cloud, or address both needs at the same time.
When the goal is protecting a computer
For many individuals and businesses, the most important data still lives on laptops, desktops, and attached external drives.
A photographer may keep active projects on a workstation. A consultant may store client files locally. A small business may rely on employee laptops as the primary location where work is created and managed.
In these situations, the primary concern isn’t cloud infrastructure. It’s protecting the device where the work happens.
That’s where Backblaze Computer Backup fits.
Computer Backup is designed to automatically protect data stored on a Mac or Windows computer, including connected external hard drives (but not NAS devices). Once installed, it runs continuously in the background, backing up files without requiring users to manually manage folders, storage allocations, or backup schedules. For organizations looking to protect NAS data, B2 Cloud Storage can serve as a backup destination through a variety of supported third-party backup and sync tools.
The value becomes clear when something goes wrong:
A laptop is stolen.
A hard drive fails.
Files are accidentally deleted.
A ransomware attack impacts local data.
A computer needs to be restored after a hardware issue.
In each case, the goal is recovery.
Computer Backup is often a good fit when:
Your most important data lives on a computer.
You want automatic, continuous protection.
You need to recover from device loss, hardware failure, or accidental deletion.
You want a solution that requires minimal administration.
Your primary concern is protecting endpoints.
For many professionals, families, and small businesses, those requirements align closely with their day-to-day reality.
When the goal is storing and managing data in the cloud
As organizations grow, data often becomes less tied to individual devices.
Files are shared across teams. Backup software protects servers and NAS devices. Applications generate and consume data continuously. Data needs to remain accessible and manageable independent of the original device, whether that’s for long-term retention, team access, application workflows, or infrastructure backups.
At that point, the challenge shifts from protecting a computer to managing data itself.
That’s where Backblaze B2 Cloud Storage comes in.
Unlike endpoint backup, cloud object storage is designed to store data independently of any single device. Data can be uploaded, accessed, managed, shared, and integrated into workflows across users, systems, and applications.
Organizations use B2 Cloud Storage for a wide range of use cases, including:
In these environments, accessibility, scalability, and integration often matter just as much as protection.
B2 Cloud Storage is often a good fit when:
Data needs to exist independently of a specific computer.
Multiple users or systems require access.
You need API-based access and automation.
You use third-party backup software that requires cloud object storage.
You need centralized storage for growing datasets.
You are building applications or data-driven workflows.
The focus isn’t on protecting a device. It’s on providing a durable, accessible home for data.
Understanding the data lifecycle
One reason organizations often use both backup and cloud storage is that data requirements change over time.
Consider a video production team.
While a project is actively being edited, the files may live on a workstation and several external drives. During that phase, protecting the editing environment is critical.
Once the project is complete, however, the priorities often change. The team may need to retain the content for future revisions, client requests, or compliance purposes. The files are no longer active, but they still need to remain available.
The same pattern appears across industries.
Architectural firms retain project files after construction is complete. Marketing teams archive campaign assets. Businesses preserve records for operational or regulatory reasons.
Not all data serves the same purpose throughout its lifecycle.
Active data often benefits from continuous endpoint protection, particularly when it lives on laptops, workstations, or attached drives. As that data ages, becomes shared across teams, or moves into long-term retention, cloud storage often becomes a more appropriate solution.
This is one reason many organizations use both Computer Backup and B2 Cloud Storage. The two solutions address different stages of the data lifecycle rather than competing for the same role.
When your storage requirements change
A common misconception is that organizations eventually “graduate” from backup to cloud storage. In reality, most environments become more complex over time, adding new requirements rather than replacing existing ones. As data volumes grow, teams collaborate across more systems, and retention needs increase, organizations often find themselves adding cloud storage to support those evolving demands. The shift isn’t typically about moving away from backup—it’s about addressing new use cases that emerge as data becomes more distributed, accessible, and valuable to the business. Common signs that additional cloud storage may make sense include:
Your data is no longer centered around one device
When multiple people need access to the same information, storing everything on a single workstation becomes limiting.
You’re building long-term archives
Completed projects, historical records, and large media libraries often benefit from dedicated cloud storage.
You’re adding automation and integrations
Applications, backup platforms, and workflows frequently require API-accessible storage.
You’re managing more than endpoints
As NAS devices, servers, and infrastructure become part of the environment, storage requirements often extend beyond individual computers.
In these scenarios, cloud storage isn’t replacing endpoint backup. It’s addressing new requirements.
The blind spot many cloud storage users discover
The reverse scenario is also common. An organization adopts cloud storage and establishes a centralized repository for important data, only to discover that important risks still exist at the endpoint level. An employee may accidentally delete a local project folder, lose a laptop, or experience a workstation failure before files have been synchronized elsewhere. Cloud storage protects the data stored in cloud storage, but it does not automatically protect every device where work is created. This is one reason endpoint backup remains an important part of many modern data protection strategies. The risks are different, and each solution is designed to address a different recovery scenario.
Why many organizations use both computer backup and cloud storage
One of the most persistent myths in data protection is that a single tool should solve every challenge. In practice, resilient environments are typically built in layers, with different solutions addressing different risks and recovery scenarios. Employee laptops may be protected with Computer Backup, while a NAS backs up to B2 Cloud Storage. Completed projects may be archived in the cloud while active work remains protected on local devices. Together, these layers create a more comprehensive approach to protecting data throughout its lifecycle.
Example: Creative teams
For creative teams, active projects often live on editing workstations and attached storage where they are constantly being updated. Computer Backup helps protect that work in progress, while completed projects can be moved to B2 Cloud Storage for long-term retention, future revisions, or client requests. This approach allows teams to safeguard current work without keeping every finished project on production systems.
Example: Growing businesses
As businesses grow, their data often becomes distributed across employee devices, shared storage, and business applications. Computer Backup can help protect employee endpoints where work is created, while B2 Cloud Storage provides a centralized location for shared assets, backups, and archives. Together, they support both day-to-day operations and longer-term data retention needs.
Example: IT and infrastructure teams
IT teams frequently manage a mix of endpoints, servers, NAS devices, and other business systems. In these environments, B2 Cloud Storage often serves as a destination for infrastructure backups, while Computer Backup protects employee devices that may not be covered by server or storage backup workflows. Rather than competing with one another, the two solutions often work together as part of a broader data protection strategy.
A quick comparison
Question
Computer Backup
B2 Cloud Storage
Is the primary goal protecting a computer?
Yes
No
Is it designed to protect endpoint data automatically?
Yes
No
Is the data primarily tied to a specific device?
Yes
Not necessarily
Is it designed for shared access across users, systems, or applications?
No
Yes
Is API access a core feature?
No
Yes
Can it serve as a destination for third-party backup tools?
No
Yes
Is the primary goal storing and managing cloud-resident data?
No
Yes
Choosing the right solution
The decision ultimately comes down to what you’re trying to protect and how your data is used.
If your primary concern is recovering files from a lost, stolen, damaged, or compromised computer, Computer Backup is likely the right starting point.
If you need scalable cloud storage for archives, applications, infrastructure backups, or shared datasets, B2 Cloud Storage is likely the better fit.
And if your environment includes both endpoints and cloud-resident data—as many organizations do—you may benefit from using both.
The most effective data protection strategies rarely rely on a single layer. They account for where data is created, where it lives, and how it needs to be recovered.
Understanding those requirements is often the first step toward choosing the right solution.
Extensive news coverage and analyst reports on AI missing productivity and ROI targets mean that AI failure is something of a hot topic. There’s no arguing that some AI initiatives are misguided, including replacing entire specialist teams with AI. For others, the issue actually lies with data knowledge and readiness–Gartner predicts that through 2026, organizations will abandon 60% of AI projects unsupported by AI-ready data, and S&P Global recently highlighted the importance of ingesting previously overlooked or unknown data to discover interdependencies in risk management.
The pressure to move at the perceived speed of AI makes it easy to skip or rush important prep work. Now that major AI pilots have been up and running, supplementing or sometimes entirely replacing select business functions with mixed results, this exposes an already known problem among AI experts: implementing AI too quickly and ignoring the importance of keeping human experts in the loop increases your threshold for error. This is especially prevalent for both internal AI tools that are meant to augment key roles, and customer-facing AI applications that are supposed to increase accessibility to an outcome, such as generating a lifelike video based on natural language prompts.
What’s causing this? It’s not just the LLMs–it’s the data. Now that human experts are more aware of what AI can get wrong, we’re going back to basics to help you get it right. This starts at the very beginning: curating, ingesting, and storing data using infrastructure that’s actually designed for moving data quickly, and without financial penalty.
Data ingest is the process of any type of data being added to a designated collection destination, whether that’s a specific file folder, database, or object storage bucket. For a lot of applications, data ingest is frequent or nearly constant–busy e-commerce sites with a constant flow of customer transactions and feedback, live video feeds, and combining real-time data sources like pairing security footage with physical building security sensors. This is called streaming ingestion–and streaming ingestion being the foundation of data collection for various types of AI is one of the key reasons why storage is an AI infrastructure problem that often flies under the radar until there’s a serious problem.
Streaming ingestion requires constant low-latency access to the data storage repository to prevent data upload lags and errors.
Streaming ingestion for video and other large files requires high rate limits and high-throughput networking capabilities to optimize upload times, especially when an application requires a file to be ready for processing in seconds/minutes instead of hours/days.
Running out of storage capacity is not an option for model performance, and for compliance and auditing purposes–streaming ingestion requires constant access to storage that is as close to infinite as possible.
Automation from the start
In addition to the files themselves, setting up a highly effective AI data pipeline involves building automation from the very beginning to immediately allocate files to the right bucket using taxonomy and collect and store file metadata to begin data aggregation critical for future labeling and processing.
Why taxonomy is critical for AI
The file itself is the data source. Navigating your dataset starts with implementing a taxonomy that makes your dataset highly searchable as your data grows from a few thousand for your first round of training to millions for an AI application operating in production.
Taxonomy is essentially your file storage structure, or how files are automatically “nested” and relationships between files are built immediately upon ingest. When you’re just getting started, developing your taxonomy helps you stay organized and ready to go searching for a specific file when your coworker doesn’t believe what the data is saying. When you’re working in established teams, implementing a new taxonomy or showing that you understand the importance of following an established taxonomy builds a contract of understanding between you and your data engineering or ML teams. (AKA, changing taxonomy mid-project is a big undertaking with ripple effects, and should not be taken lightly.)
A simple example taxonomy for ingesting raw files can look like this:
/<source>/<modality>/<status>/<date>/filename
Taxonomy should also reflect what the data is actually doing or will do, not just the file type and data source. The goal is to make every object self-describing at write time, so downstream training pipelines can filter, version, and partition without touching the data itself.
Partition by date/time at the prefix level so you can use time-range queries and lifecycle rules without scanning everything
Include modality (video, audio, image, text) as a top-level segment so cross-modal datasets stay logically separated but co-located in the same bucket
Use a UUID or content hash as the filename — never rely on source filenames, which are inconsistent and collision-prone at scale
Use B2 bucket policies or object tagging rules to reject objects written to non-conforming prefixes
Maintain a human-readable taxonomy manifest (taxonomy.json at bucket root) that documents each top-level prefix and its schema
For video specifically, consider a separate prefix segment for resolution or codec: …/video/4k/h264/… — this pays off quickly when training jobs need to filter by input spec
Retain all the metadata
Write metadata as object tags and custom headers at ingest using per-object user-defined metadata at PUT, such as:
This way, the metadata travels with the object and is always returned on HEAD requests without a separate lookup.
But to build out a rich dataset, you will need even more metadata in the form of sidecar metadata files. Retain annotations, bounding boxes, ground-truth labels, licensing info, and consent flag metadata by creating a sidecar JSON with a .meta.json suffix. For the warehouse camera video example listed above, you would end up with two files that look like this:
Enable object versioning on training buckets. If a labeling pipeline updates an annotation, it should write a new version (or a new sidecar) rather than overwriting — training reproducibility depends on knowing which metadata was present at the time a dataset was compiled.
Expose metadata to training pipelines via a manifest
Rather than having training jobs scan bucket prefixes directly, generate a manifest file (JSONL or Parquet) at the end of each ingest batch that enumerates every object key + its full metadata. Tools like PyTorch’s WebDataset and HuggingFace datasets can load directly from these manifests, and it decouples the training job from needing object storage credentials for discovery.
Deciding on storage while evaluating data
To summarize, this is why choosing your storage destination based on your current (or, if you’re already undergoing a data management transformation, future-state) scenario is critical:
Ingest type: Does your storage provide enough network bandwidth to capture the correct type of data in real time (especially for video?)
Data type: Will large files potentially incur large upfront costs with upload fees?
Data processing workflow: Does your storage have capacity headroom for file multiplication during processing, and does the cost structure allow this to happen without potentially draining infrastructure budgets?
Even with Backblaze B2’s hot storage at cold storage pricing, it may be beneficial for you to tier your storage based on your ingestion type, and how frequently the data will be accessed for training.
Batch ingestion is better suited for mid to lower performance storage, as this is typically used for historical datasets or a set schedule of pre-determined data updates, such as jobs pulling from relational databases or CSV uploads once a day or once per week.
Streaming ingestion is well-suited for hot storage to support a continuous stream of real-time (or near-real-time) data processing, such as from social media feeds and high-volume e-commerce AI helper agents.
Hybrid ingestion uses a combination of batch and streaming ingestion to handle both historical and real-time data requirements for AI models.
Surprise retrieval penalties for model training can happen even while building out your MVP or proof of concept–so avoid a storage headache and start building your pipeline at data ingest with Backblaze B2 $6.95 per TB/month. Create an account to get started with 10GB for free, or contact our storage experts for assistance with migrations and more.
Looking for more info on data ingest? Watch the on-demand webinar that dives into more details about data ingest with Backblaze’s Director of Applied AI Jeronimo De Leon.
Welcome to the Q2 2026 Network Stats report. While we’ve been tracking trends since December 2023, this is the third quarter since we operationalized the dataset and re-launched the series, allowing ourselves to make direct, quarter-over-quarter comparisons. Why? Because AI workloads were changing traffic patterns across Backblaze’s network, and reshaping the internet.
With three quarters of historical data now available, we’re moving beyond measuring traffic volumes. We’ve been able to spot trends and start drawing conclusions—how predictable or unpredictable those workloads really are, and what that means for infrastructure that supports the next generation of AI applications.
Check out past Network Stats reports
If you’re interested in some of the trends we’ve spotted in previous reports, you can review the past reports here: Q1 2026 Q4 2025 Q3 2025
Previous analysis has been based on the amount of network traffic in bits flowing across in or out of our network, the number of bits and participants per TCP session (our coined “magnitude” metric), and regional geographic trends. In this report, you’ll find charts and heatmaps for the metrics that we’ve been reporting on over the past year, but we’re also going to use statistical analysis to answer a practical question: What kinds of traffic patterns do AI workloads create, and how should infrastructure evolve to support them?
Traffic from neocloud and hyperscaler networks are proving to be very dynamic in nature, and that’s what we’re going to explore in this quarterly report: variance.
Join the webinar
Want to hear more? Join Brent Nowak, Manager, Network Engineering, and Stephanie Doyle, Sr. Manager, Market Intelligence and Keeper of Stats, live on Tuesday, July 28, 2026 at 11:30 a.m. PT / 2:30 p.m. ET to walk through the data and spot the latest trends.
Can’t make it live? Register anyway and we’ll send you the recording.
Why look at variance?
Variance is a deep topic to explore, which involves modeling our traffic patterns against a known baseline. To analyze variance, we built a new time-series dataset using 10-minute traffic samples and modeled traffic behavior against statistical baselines. This lets us distinguish stable, predictable traffic from highly volatile workloads that demand different infrastructure planning.
I refreshed my statistics knowledge, created a new database to hold a timeseries dataset, and spent a few nights experimenting with the SciPy Python library in order to not only produce pretty graphs, but to generate a signal for us to interpret.
The types of questions that we’re interested in answering from the variance signals that affect our business include:
How quickly are AI workloads changing capacity requirements?
Which traffic patterns require different network architecture? And does our current architecture support what we’re growth modeling into the future?
Which signals represent lasting trends versus temporary spikes?
These are big questions! And exciting ones as Backblaze looks to support today and tomorrow’s workflows.
With that, let’s refresh our existing charts with this quarter’s data before diving into the new analysis on variance.
Summer heat-up
The stacked area graph below shows total traffic by network type over time updated with the most current data.
Total traffic by network type.
CDN traffic: New baseline of activity with a 66% increase from last year.
Hosting traffic: The hosting category (the light orange layer right above CDN) has remained incredibly rigid. Unlike neocloud or hyperscalers, which expand and contract elastically, hosting traffic has maintained a nearly identical bandwidth footprint for over a year.
Hyperscaler traffic: Hyperscaler traffic also followed the neocloud pattern, with the lowest amount of activity in January and remaining steady into June. Internal data sources show new workloads across all of the major hyperscalers in the past quarter.
Neocloud traffic: After a low point of activity in January, activity increased rapidly into March and has remained high until June. Internal telemetry shows that not only the amount of neocloud traffic increased in Q1 into Q2, but the number of neoclouds that we are interacting with has increased.
ISP-regional traffic: This was the dominant driver of the massive traffic spike in October 2025. While it dropped significantly into January 2026, it has aggressively rebounded through Q2 2026 and is currently the largest single driver of volume alongside neocloud.
Migration traffic: This traffic includes one way migrations into our environment, primarily serviced by partners such as Flexify.IO. We have migrations running all the time, but we can visually see large amounts around November 2025 and March of 2026.
Over the entire one-year graph range, Backblaze’s total platform traffic experienced volatility, peaking in October 2025 before seeing a multi-tier contraction down to a January 2026 winter baseline. Following this, in both Q1 and Q2 of 2026 we’ve observed an increase of activity led by a rebound in ISP-regional and AI-focused neocloud traffic. An additional standout is CDN traffic, which achieved a permanent and substantial new activity baseline, growing roughly 66% year-over-year.
Heatmaps: How and where data moves
To better understand our network activity, we isolated variables like region and types of provider. Here are the standard definitions we use each report:
Total traffic volume: Where did we send and receive the most traffic?
Magnitude: Where were the data transfers with the most bits per unique IP address?
Uniqueness: What does the number of distinct IP addresses look like?
Quick terminology refresher
Regions US-West: Our largest and longest-running region US-East: Region with the most observed proximity to neocloud infrastructure CA-East: Our newest region in Canada. EU-Central: Our EU region.
Network Types CDN: Networks that use Backblaze as an origin store for content delivery. Hosting: Traditional hosting providers that runs workloads like physical or virtual servers for web, database, or application tasks. Hyperscaler: Large, traditional cloud providers. ISP-regional: Local or regional ISPs; think of these as the “last mile” paths as these networks are very close to customer equipment and efficient. ISP Tier1: National or international ISPs that carry our traffic long distances. Neocloud: AI-focused compute networks.
Heatmap #1: Where did we send and receive the most traffic?
ISP-regional traffic is a hotspot for US-West, as expected. This region has the largest internet exchange (IX) and server footprint behind it. Neocloud traffic remains concentrated in the US-East, but for this quarter traffic increased in the US-West and EU-Central regions. Another standout this quarter is more hyperscaler activity in EU-Central than the previous quarter.
Total number of bits transferred across our regions to each network type for Q2 2026.
Heatmap #2: Where were the data transfers with the most magnitude (bits per IP address)?
Another metric we record is bits per IP or what we term “magnitude.” This combination of the amount of traffic transferred with how many actors are involved per network is a good proxy to measure how heavy or impactful individual data flows are. In short:
High volume, many IPs: Easier to distribute and load-balance across infrastructure. And many source and destination pairs means that we can traffic engineer at the WAN layer, sending some traffic over one provider and some over another.
High volume, few IPs: More difficult, but more interesting, from a NetEng perspective.
Traffic magnitude is currently a driver of decisions for capacity and growth plans. Our US-East region continues to have a high concentration of high bandwidth transfers between a small number of hosts. New for this quarter is an uptick in traffic magnitude in our EU-Central region.
This could be an indication of more geographic spread of AI related workflows as for every quarter that we’ve reported on the metric value, we have seen more diversity into US-West and EU-Central outside of the concentration in US-East. We will continue to watch this trend.
Magnitude transferred across our regions to each network type for Q2 2026.
Heatmap #3: How many unique addresses do we interact with?
Not every graph or heatmap has to show something dramatic. Sometimes it’s good to see exactly what you expect quarter over quarter in a data series. This is especially true for our uniqueness metric, measuring the number of distinct IP addresses per network time.
We interact with the most number of parties out of our US-West region. It’s the most mature and serves a large amount of ISP-regional consumers, so the consistency of the uniqueness metric is a good sanity check on our dataset.
US-West shows the highest overall uniqueness, driven by its larger number of data centers and mix of workloads.
Neocloud traffic, by contrast, tends to involve fewer, more persistent endpoints, consistent with AI pipelines that rely on stable, long-standing connections between storage and compute.
Communication uniqueness across our regions to each network type for Q2 2026.
Neocloud and hyperscaler traffic vs predictive patterns
This next set of charts shows a deeper dive into the metrics associated with neocloud and hyperscalers over time. The contrast between a more “traditional” workload (e.g., CDN, hosting, and ISP regional traffic) and emerging trends with neoclouds and hyperscalers is the easiest place to see the shift in network traffic profiles. The latter represents bursty, high magnitude traffic that reshapes conversations around network planning.
Chart #1: What’s the magnitude of neocloud and hyperscaler traffic over time?
Hyperscaler and neocloud network magnitude May 2025 – May 2026.
Following a highly concentrated, low-magnitude baseline for both categories in January and February 2026, Q1 closed with a dramatic March surge where several individual neocloud networks spiked massively.
Moving into Q2 2026 (April through June), while the absolute highest neocloud peaks compressed slightly downward compared to that March anomaly, the overall volume of high-magnitude neocloud workflows multiplied significantly, resulting in a much denser cluster of active endpoints staying consistently high quarter-over-quarter.
Hyperscaler endpoints experienced a steady and noticeable upward move over the course of Q2, with multiple data points breaking out of their typical floor by May and June.
Ultimately, neocloud retained its dominant, high-magnitude presence across both Q1 and Q2 quarters, while hyperscalers saw a distinct and steady escalation in individual workload sizes.
Heatmap #1 and #2: How dynamic are neocloud and hyperscaler traffic patterns?
Neocloud related traffic continues to show strong concentrations in our US-East region with recent growth March into June. Hyperscaler traffic is the most variable when we compare it to last quarter’s heatmap. There is a new, more distributed concentration across all our three largest regions—US-East, US-West, and EU-Central.
Together with the trends we’ve reported over the past year, these results suggest AI workloads on the Backblaze network are becoming geographically more distributed rather than remaining concentrated in a single region. Note the caveat: it’s possible, even probable, that there’s a macro trend about geographical dispersion of AI data, but it’s important also that Backblaze has become increasingly known as a trusted infrastructure provider specifically in this space.
Layer on the fact that AI workloads can be reflective of fewer players with more data (see also: magnitude or elephant workflows), and what you have is difficulty understanding whether this is a macro trend, or Backblaze specific. We’ll keep our eyes on the data as it develops.
Neocloud monthly traffic totals by region for May 2025–June 2026.
Hyperscaler monthly traffic totals by region for May 2025–June 2026.
Heatmap #3, #4, and #5: How dynamic are CDN, hosting, and ISP-regional traffic patterns?
We’re grouping CDN, hosting, and ISP regional types together because they represent a “steady-state” for us as network operators. These patterns are predictable, spread out over time, and generally do not change month-to-month.
For Q2, we saw the concentration of CDN in US-West remain steady with traffic growth in our US-East region. Hosting traffic is showing a new pattern, with more activity in our EU-Central region starting in April into June.
CDN monthly traffic totals by region from May 2025–June 2026.
Hosting monthly traffic totals by region for March 2025–June 2026.
ISP-regional monthly traffic totals by region for March 2025–June 2026.
Variance study methodology
For our new variance study we needed more granular traffic sampling data than aggregated weekly or monthly totals. Ten minute sample data gave us a balance between sampling fidelity, data warehousing storage, and query time when iterating on the project idea.
Here’s a sample of anonymized data in one region, for one hour, for one ASN (network), with ingress and egress 95th bitrate percentage values:
Anonymized Timeseries Sample Example
datetime
region
asn
ingress
egress
2026-05-01T00:00:00
us-east
asn-number
4408643576.86
72810025561.08
2026-05-01T00:10:00
us-east
asn-number
4202884722.26
72153643081.09
2026-05-01T00:20:00
us-east
asn-number
4282470297.97
72840197796.70
2026-05-01T00:30:00
us-east
asn-number
4462602109.34
74194149854.89
2026-05-01T00:40:00
us-east
asn-number
4011477298.04
73431072317.13
2026-05-01T00:50:00
us-east
asn-number
3919542094.52
71051545108.21
Understanding the use of variance
Raw traffic metrics (total gigabits per second) tell us how much data is moving. Variance tells us how consistently it moves.
Stable traffic is easier to plan for. Highly variable traffic requires more flexible network design and additional capacity planning—it reflects the bursty nature of AI training and inference workflows, where compute clusters can scale rapidly and move enormous datasets over short periods.
Here’s how to read the analysis:
The shape of the bell curves (right column): A very tall, narrow peak indicates low variance. This means the traffic behaves predictably and stays clustered close to its baseline average. A short, wide, flattened curve indicates high variance, meaning the traffic is highly volatile, subject to massive sudden swings, and much harder to provision for.
The interplay of ingress vs. egress (left column): By overlaying both metrics, we can immediately spot structural imbalances. For instance, if one direction has a sharp spike (low variance) while the other is flat and wide (high variance), it signals that asymmetric network events are dominating that infrastructure type.
Below is a sampling of network data in one point in our network over the month of May 2026, with the traffic pattern graphed on the left side and variance on the right side. Immediately we can see different groupings of patterns. For readability and grouping, we’ve separated the types of networks into two categories: the dramatic and the reliable.
Bringing the drama: Hyperscaler and neoclouds
AI infrastructure behaves differently than traditional internet infrastructure. The following comparisons illustrate why.
Hyperscaler and neocloud traffic and distribution variability.
So, what can we learn from this? Let’s examine it by network type.
Hyperscaler: High egress volatility with balanced ingress
Ingress traffic remains tightly controlled around the baseline (sharp dashed peak). However, egress traffic (solid line) shows a flattened, high-variance spread.
The time-series chart reveals constant, jagged fluctuations between 50 Gbps and 150 Gbps, indicating highly bursty customer data retrieval patterns throughout the month.
Neocloud: Synchronized, moderate volatility
Both ingress and egress display structurally similar, moderately wide bell curves. This reflects a well-proportioned network footprint where data-in and data-out scale together.
The time series demonstrates sustained high baseline volumes (Total traffic consistently tracking between 200 Gbps and 350 Gbps) with continuous business-hour cyclical wave patterns.
As network operators we’re using this type of real-world data to help drive our connectivity footprint decisions. Large, bursty traffic patterns are best served by PNI network connections. PNIs allow us to isolate workflows to a distinct physical egress/ingress path in our network, which enables us to be able to more easily route, load-balance, and support these higher performance profiles. That translates into more predictable performance for customers running bandwidth-intensive AI workloads.
We have a high interest in connectivity to partners in our US-East location, as it is located in the Ashburn-Reston datacenter corridor near a lot of existing datacenter campuses. This one again reinforces the notion that geography plays an important role in where entities are placing their data and compute engines rather than the nondescript “cloud”.
If you’re interested in learning more about the geography of neocloud traffic, visit the Q1 2026 report and review the “Where in the world is the neocloud?” section.
Let’s switch over to our three other major network types that we also want to profile for capacity, performance, and scalability considerations.
Bringing the predictability: CDN, hosting, and ISPs
CDN, Hosting, and ISP-Regional traffic and distribution variability.
CDN: Extreme ingress stability vs. massive egress spread
The ingress curve is a razor-thin needle at 0 Gbps variance, proving inbound management traffic is perfectly flat. Conversely, the egress curve is completely flattened across the entire -50 to +50 Gbps spectrum.
This is textbook CDN behavior: steady, quiet ingest lines paired with massive, erratic client-side distribution demands peaking near 600Gbps.
Hosting: Highly predictable footprint with asymmetric egress stability
Inbound traffic displays a slightly wider variance profile, while outbound traffic (egress) forms a remarkably sharp, low-variance peak.
The time series shows a tight, rhythmic diurnal cycle for egress down near 25Gbps, while ingress experiences a steady climb over the course of May, rising from a 75Gbps baseline up past 125Gbps.
Regional consumer traffic demonstrates an ultra-low variance spike on egress, maintaining a very steady floor near 75Gbps. Ingress traffic carries slightly higher variance but remains highly constrained to predictable diurnal rhythms.
This represents localized residential/commercial end-user ingress cycles, peaking consistently between 400 and 500 Gbps every single day.
Signals in the noise
This far into Network Stats, the biggest takeaway isn’t simply that there is more traffic because of AI. It’s that AI traffic has different—and still emerging—patterns compared with traditional cloud workloads. It’s more bursty, more geographically concentrated, and less predictable. Understanding those patterns helps us decide where to add capacity, when to upgrade interconnects, and how to design a network that can support tomorrow’s AI applications—not just today’s.
As our dataset continues to grow, we’ll keep refining these models and sharing what we learn. Each quarter gives us a clearer picture of how AI infrastructure is evolving, and how cloud storage networks must evolve alongside it. Let us know what resonates, what questions you have, and what patterns you’re seeing in the comments section.
And, if you want to stay connected to this and other kinds of technical reporting from Backblaze, check out our Developer Newsletter.
You’ve done the storage evaluation. The per-terabyte price is right. The durability numbers check out. Compliance boxes are ticked. And still, the cloud migration project hasn’t been approved.
That’s not a coincidence.
The cloud storage industry has spent years competing on what happens after you’re already locked in: performance, redundancy, features. Almost nobody competes on what it costs to get there—or what it costs to leave.
Migration friction isn’t an oversight. For most hyperscalers, it’s a business model.
Why cloud migration projects stall before they start
The business case for cloud storage usually looks solid on paper. Lower per-terabyte costs. Less hardware to maintain. A path off aging tape libraries and overloaded NAS environments.
Then someone runs the actual migration math.
Egress fees from the current provider. Data transfer charges. Migration software licenses. Professional services. Tape digitization. Internal engineering hours. Project coordination overhead. For a large dataset, those costs can erase years of projected storage savings before a single byte moves.
Teams spend months building an approval-ready business case, only to find the upfront migration cost makes the model unworkable. The project stalls. Infrastructure the organization already knows is unsustainable stays in place. Modernization gets pushed to next quarter.
This is where most cloud vendors win. The storage decision becomes moot if the organization can never afford to move.
How egress fees trap organizations with their current provider
By the time most IT teams discover what cloud egress fees actually cost, they’re already mid-negotiation with a new provider.
The pricing model is deliberately asymmetric: getting data in is cheap, often free. Moving it out is where providers charge—and for multi-petabyte environments, those charges can run to hundreds of thousands of dollars before a migration has even started. Technically, the organization owns its data. Financially, moving it is a different question.
This reframes the evaluation in a way that favors incumbents. The question stops being which platform best fits long-term needs and becomes whether the organization can afford to leave at all. Once you’re in a major cloud platform with a large archive, exit costs are a structural retention mechanism.
Ask any prospective provider, early: what does it cost to leave? If they’re vague, that’s the answer.
How long does a cloud data migration actually take?
Cost gets scrutinized. Time usually doesn’t—until a migration is already underway and slipping.
A large-scale migration means inventorying data and metadata, evaluating and procuring tooling, coordinating across vendors, monitoring transfer jobs, validating integrity at the destination, and troubleshooting the inevitable edge cases. For multi-petabyte environments, self-managed projects routinely stretch from months into years.
Every quarter that drags on is a quarter the organization is paying to maintain infrastructure it’s already committed to replacing, while its engineering team runs a file-moving operation instead of working on anything strategic. The total cost of a slow migration almost always exceeds the initial estimate—and almost nobody builds that into the business case upfront.
What actually goes wrong during cloud data migration
Migration risk tends to be underestimated until something breaks.
The core questions—will files transfer without corruption, will metadata survive intact, will dependent applications keep working—are harder to answer than they look for LTO tape archives that haven’t been accessed in years, NAS and SAN environments with proprietary metadata structures, media archives with irreplaceable assets, regulated content with chain-of-custody requirements, and datasets large enough that verification at scale is its own engineering problem.
The cost of getting this wrong isn’t just the migration itself. Data loss, integrity gaps, or application failures discovered post-migration can be significantly more expensive than any egress fee. Validation and verification need to be designed into the plan before transfers start, not bolted on after something fails.
Why most cloud providers leave migration to you
Infrastructure teams evaluating cloud storage aren’t looking for a transfer tool. They want infrastructure modernized without burning their engineering team on a multi-year internal project. Predictable costs. A path to cloud that doesn’t require standing up a program management office just to move data.
The standard provider response is documentation and an onboarding checklist. After that, you’re largely on your own.
This isn’t an accident. Selling storage is straightforward. Owning migration means taking on cost, risk, and operational complexity that most providers would rather leave with the customer. The economics of the business favor making entry easy and exit expensive, with as little friction to growth as possible in between.
Providers that treat migration as their problem to solve are a different category. They’re betting that making it genuinely easier to get to their platform is worth more than one-time migration revenue—because a customer who gets there successfully tends to stay.
How Backblaze Universal Data Migration works
We built Universal Data Migration because we kept seeing the same thing: organizations that had already decided to move to Backblaze B2 getting stuck on the migration itself. The technology decision was made. The budget was approved. The project just couldn’t get started.
The program moves data from virtually any source—AWS S3, Microsoft Azure Blob, Google Cloud Storage, Wasabi, NAS and SAN, file servers, LTO tape across all generations, physical hard drives, legacy archives—with Backblaze managing the process rather than handing the customer a tool and a runbook.
The migration cost doesn’t have to be a reason the project stalls. That’s the point.
Before you sign a cloud storage contract, ask these two questions
The storage evaluation isn’t complete until you know what it costs to get there and what it costs to leave.
Most providers make the second number hard to find. If you have to dig for egress pricing, or if a sales rep answers the exit question with “we’d work with you on that,” build the worst-case number into your model before signing anything.
The right provider won’t make you ask. They’ll make migration part of the conversation from the start—because they’re confident enough in their platform to compete on the full picture, not just the monthly storage line.
Have a migration project that keeps getting pushed?Talk to our team about what it would actually take to move your environment to B2.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.