Amazon Threat Intelligence identified a PHP2Shell exploitation attempt dating to Oct. 17, 2026, in MadPot telemetry, four days before public disclosure of CVE-2026-109618 and CVE-2026-109619. The exploit attempt originated from an IP address associated with a commercial anonymization network. While the vulnerability was under embargo, the targeting of a honeypot from an anonymized IP address suggests the activity was conducted by a threat actor, though it remains unclear how the actor acquired exploit information prior to disclosure.
The PHP embargo window was set to be lifted on 2026-10-21 1400 UTC. On the day of the release, Amazon Threat Intelligence identified multiple proof of concept exploits for the vulnerability, with the earliest around 2026-10-21 0200 UTC. Subsequently, from 2026-10-21 0200 UTC to 2026-10-21 0800 UTC, Amazon Threat Intelligence identified additional exploitation attempts of PHP2Shell targeting MadPot from additional anonymized infrastructure. The actual payloads and choices in anonymization infrastructure varied, suggesting these were multiple actors. Technical analysis is ongoing, and it’s unclear if any of these attempts would have succeeded in real-world systems.
The actual release of the embargo window was 2026-10-21 1400 UTC. Once the embargo was lifted and the patch was released, additional proof-of-concept exploits appeared within hours, and we saw them used against our sensors almost immediately. PHP2Shell is now being broadly exploited in the wild.
Two lessons from this event apply well beyond this one vulnerability:
An embargo protects defenders only until someone else finds the same bug. Coordinated disclosure is still the right model. But defenders should not assume the public disclosure date is the earliest date of exploitation. With PHP2Shell, compromise may predate the advisory.
The time from patch to working exploit is shrinking for structural reasons. In the past, most exploitation we observed came after a public proof of concept was released. A small number of capable actors built exploits, and everyone else waited for them. That dependency is weakening. AI-assisted analysis makes it cheaper to turn a patch diff or advisory into a working exploit. As a result, more actors can act within hours or even minutes once technical details of a vulnerability are disclosed.
For security leaders, this changes several working assumptions:
For critical vulnerabilities in internet-facing systems, measure patch and mitigation timelines in hours. A 7-day or 30-day SLA assumes a delay that no longer exists.
Start investigations from the earliest known exploitation, not from the disclosure date. For PHP2Shell, investigate from at least starting on October 17th.
Invest in detections that don’t rely on a signature for a specific CVE. The first exploitation will often come before those signatures exist.
How AWS helps protect customers
AWS deploys multiple layers of protection to help safeguard customers. Our internal threat intelligence system automatically detected and restricted malicious scanning attempts targeting this vulnerability. We analyze over 200 billion events per minute and integrate threat intelligence from our MadPot honeypot network to identify and block known exploitation attempts in real time. Our honeypot system provides us with early detection of exploitation attempts, enabling rapid response and threat analysis.
Immediate recommended actions
Upgrade immediately to the fixed PHP versions. Upgrading is the only complete remediation for both CVE-2026-109618 and CVE-2026-109619. There are no configuration-only workarounds that fully address both issues.
Consider blocking multi-part file uploads in PHP deployments that cannot be patched immediately, but determine how this would affect your application prior to deploying.
Look for POST requests with the PHP_SESSION_UPLOAD_PROGRESS string in form uploads.
Review web server logs for suspicious activity.
Check for unexpected process execution or file modification on web application servers.
Indicators of Compromise (IOCs)
IP Address
Observed Date
103.216.220.92
10/17/2026
31.223.184.166
10/21/2026
37.19.200.5
10/21/2026
134.209.159.64
10/21/2026
103.114.163.188
10/21/2026
95.217.98.37
10/21/2026
The identified IP addresses include shared anonymization infrastructure and are not exclusive to this threat activity. Organizations should investigate any observations involving these addresses as opposed to blocking.
Nothing last week added a new kind of compute. What it did instead was shorten the distance between the code you already have and that code being live. AWS Lambda learned to run a plain HTTP server with no adapter in front of it, and Amazon S3 became something you can provision from inside the tool you were already using, without opening the AWS Management Console. Different services, same direction.
The counterweight arrived on Thursday. As it gets easier to put things into production, it matters more that you can say what those things are allowed to do, and this week’s most interesting read is about exactly that. Now, let’s get into this week’s AWS news…
Headlines
AWS Lambda Web Functions is a new form factor that runs a standard HTTP web application on Lambda without rewriting it into an event handler. You take a port-listening server built with Express, Hono, Fastify, or Next.js, run aws lambda-web deploy, and get back a live HTTPS URL in under a minute. No adapters, no infrastructure to set up first, no framework lock-in. Lambda now has three form factors on the same Firecracker isolation, which compose inside one application: Event Functions (the model you already know) for async work, Web Functions for the user-facing layer, and MicroVMs for stateful sandboxes running untrusted code.
Two details make this more than repackaging. Each execution environment handles up to 128 concurrent requests, so a burst of traffic shares warm environments instead of mapping one request to one environment, and billing meters the CPU time your code actually uses rather than wall-clock time. For server-side rendering, API backends, and inference endpoints streaming tokens, where most of the elapsed time is spent waiting, that changes the arithmetic. Adding --regions to the same deploy command replicates your code and configures latency-based routing behind a single global URL, and you can split traffic across revisions by weight for a canary rollout. It’s available in five Regions, running Node.js 24 on Arm64 with VPC connectivity. The AWS Compute Blog has a longer walkthrough, and Amazon CloudFront can now use a Web Function endpoint as an origin with origin access control.
The week’s other headline isn’t a launch. Trust in Depth: giving agents more autonomy without losing control makes an argument I keep running into in practice: putting a person in the loop for every agent action works at small scale and then quietly stops working, because people asked to check everything stop catching what matters. The alternative is four questions answered at four moments, which AWS calls scope, know, bound, and observe. The part worth sitting with is that an agent’s limits belong outside its own reasoning, in Amazon Bedrock AgentCore policies enforced at the gateway, because an agent cannot turn off a control it does not run. AWS has run automated reasoning in production for more than a decade, including AWS Identity and Access Management at more than 2.1 billion requests per second, and the case here is for pointing it at the rules you write for agents.
Last week’s launches
Here are some launches and updates from this past week that caught my attention:
Amazon S3 is now available on the Vercel Marketplace and v0 by Vercel – You can now provision S3 general purpose buckets, S3 Tables, and S3 Vectors from the Vercel dashboard, or by describing what you want to build in v0. It joins existing integrations for Amazon Aurora, Amazon DynamoDB, and Amazon OpenSearch Serverless, so the whole stack sits in one AWS account with one bill. The authentication detail is the good part: a short-lived OIDC token is exchanged at runtime with AWS Security Token Service for credentials scoped to that resource, so no static keys are stored anywhere.
Amazon EC2 T8i instances are now available in South America (São Paulo) – The newest burstable generation reached the São Paulo Region, which matters for the unglamorous half of a workload: login gateways, small databases, CI/CD runners, low-traffic sites. Amazon EC2 T8i delivers up to 30 percent better price performance than T3, with up to 70 percent higher compute performance and 2.4 times the Amazon EBS bandwidth. It keeps the same CPU credit system as T3, so moving over is a size change rather than a redesign, and t8i.micro and t8i.small are available under the AWS Free Tier.
Reflection Beam, an open-weight model for agentic coding, is now on AWS – You can now deploy Beam, Reflection AI’s open-weight model for agentic coding and long-horizon tasks, from Amazon SageMaker JumpStart. It’s a sparse mixture-of-experts model with 501 billion total and 23 billion active parameters, released on Hugging Face under Apache 2.0, and Reflection reports an effective context length of 1 million tokens. Start with a JumpStart real-time endpoint, or use SageMaker HyperPod Inference with SGLang or vLLM when you need Kubernetes-native control. It was also ported and optimized for AWS Trainium3, and launches in N. Virginia and Ohio.
AWS Lambda Durable Execution SDK for Go is now generally available – You can now write multi-step Go workflows that checkpoint their own progress and pause for up to a year while waiting on an external event, without building progress tracking yourself. That covers deployment rollouts with approval gates and pipelines that call a model and then stop for human review. It behaves like ordinary Go tooling: go get to add it, deploy a single static binary on the provided.al2023 runtime, and test a full workflow locally with the durabletest package, no network access or credentials required.
Amazon CloudWatch announces log routing and chained log parsers – You can now define routes in an Amazon CloudWatch pipeline that send each event to a different log group based on conditions evaluated against processed fields, so severity, source, or event type can each land somewhere with its own retention and access controls. Chained parsers handle the other half: parsers run in sequence, with later ones consuming fields that earlier ones produced, so you can parse a JSON envelope first and then run a Grok parser over a field it extracted.
For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.
Other AWS news
Here are some additional posts and resources that you might find interesting:
AWS Security Agent exploited 33 of 37 new real-world CVEs – The team pointed their autonomous penetration-testing agent, now part of AWS Continuum, at 37 recently disclosed CVEs packaged as live containerized targets, starting from nothing but an endpoint URL and a one-line hint. It captured 35 flags, and after auditing every win against the challenge’s canonical proof of concept, 33 of 37 (89.2 percent) held up as genuine end-to-end exploitation. The two misses are what make the post worth your time: in both, the agent found and exploited the bug, then took the target down before it could read the flag. A capable autonomous attacker is also a destructive one.
Check your calendar and sign up for upcoming AWS events:
AWS re:Invent – re:Invent returns to Las Vegas from November 30 to December 4, with more than 2,200 sessions. The event catalog is live and reserved seating is open, so register and claim your spots before they fill up.
AWS Community Days – Community-led conferences planned and delivered by community leaders. Here in Brazil, the 2026 season closes with AWS Community Day Brasil Norte in Belém on October 31, the final stop in a year that covered every region of the country for the first time.
Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development. Browse here for upcoming AWS-led in-person and virtual events and developer-focused events.
That’s all for this week. Check back next Monday for another Weekly Roundup!
— Daniel Abib
This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!
A resilience plan is useful only while it reflects the application you run. After a migration or deployment, a service can acquire a new dependency while its documented recovery objectives stay the same. In a shared Kubernetes cluster, even deciding which resources belong to that service can take investigation.
On September 18, 2026, the Next generation of AWS Resilience Hub introduced three capabilities to help you keep workload scope and resilience requirements aligned with your running environment:
Generative AI-powered Dependency Insights analyzes a service’s discovered dependencies and highlights the patterns worth reviewing.
Resilience policy sharing through AWS Organizations lets a central team define resilience requirements once and make them available to member accounts.
In this post, you follow a team reviewing the resilience of a sample workload named checkout on Amazon EKS, representing an online store’s checkout service. The team starts by defining which Kubernetes resources belong to checkout, using labels to distinguish it from inventory in the same namespace. This establishes the resource boundary for the resilience review.
With that boundary defined, the team examines discovered dependencies and uses Dependency Insights to prioritize findings for investigation. A cross-Region dependency becomes a concrete question about whether checkout’s recovery design accounts for the services it requires to operate. The service owner then works with a central resilience team to validate the recovery requirements and apply a shared policy. Maintaining those requirements centrally gives teams a common definition to adopt across accounts, while policy events help the central team track adoption.
You perform these steps using the console or the AWS Command Line Interface (AWS CLI). The workload generates synthetic traffic to demonstrate dependency discovery.
About the application model: In the Next generation of Resilience Hub, the primary unit of assessment is a service. Services can be grouped into systems, and user journeys describe paths through them. See the key changes and the overview of the new hierarchy in the Next generation of Resilience Hub.
An Amazon EKS cluster with sample, labeled workloads and permission to configure access to the cluster.
If you follow the CLI examples, install or update the AWS CLI using the installation and update instructions. Your installation must support the resiliencehubv2 commands. These examples use Bash.
An AWS Identity and Access Management (IAM) role that Resilience Hub can assume, with the AWSResilienceHubV2AssessmentExecutionPolicy managed policy attached. The console can create this role when you create a service.
Kubernetes RBAC permissions and an EKS access entry that grant this role access to Kubernetes resources. The permissions guide provides the manifest and commands.
For policy sharing, an organization with all features enabled and access to its management account.
The examples use two accounts: a workload account containing the EKS cluster and Resilience Hub service, and a management account that owns the shared policy.
For the CLI examples, configure profiles named workload and management for the respective accounts. Replace the example cluster ARN and other placeholders with your own values, and set the Region:
export AWS_REGION=us-east-1
Each command uses --profile to select the account. Follow either the console steps or their CLI equivalents for each operation.
Amazon EKS label support for service input sources
A service input source tells Resilience Hub where to discover a service’s resources. Input sources can be AWS CloudFormation stacks, Terraform state files, resource tags, or Amazon EKS clusters. For an EKS input source, you select the namespaces to include. With this launch, you can also use Kubernetes label selectors to filter resources within those namespaces.
A namespace can contain workloads owned by different teams. With labels, you can select checkout’s resources without including inventory or reorganizing the namespace for an assessment. You use the same labels your teams already maintain.
How it works
Specify the cluster and one or more namespaces, then add label selectors to filter resources within each namespace. A selector contains a key, an operator, and values. Selectors within a namespace use AND logic: an object must match all of them. Without a selector, Resilience Hub discovers every supported object in the selected namespaces.
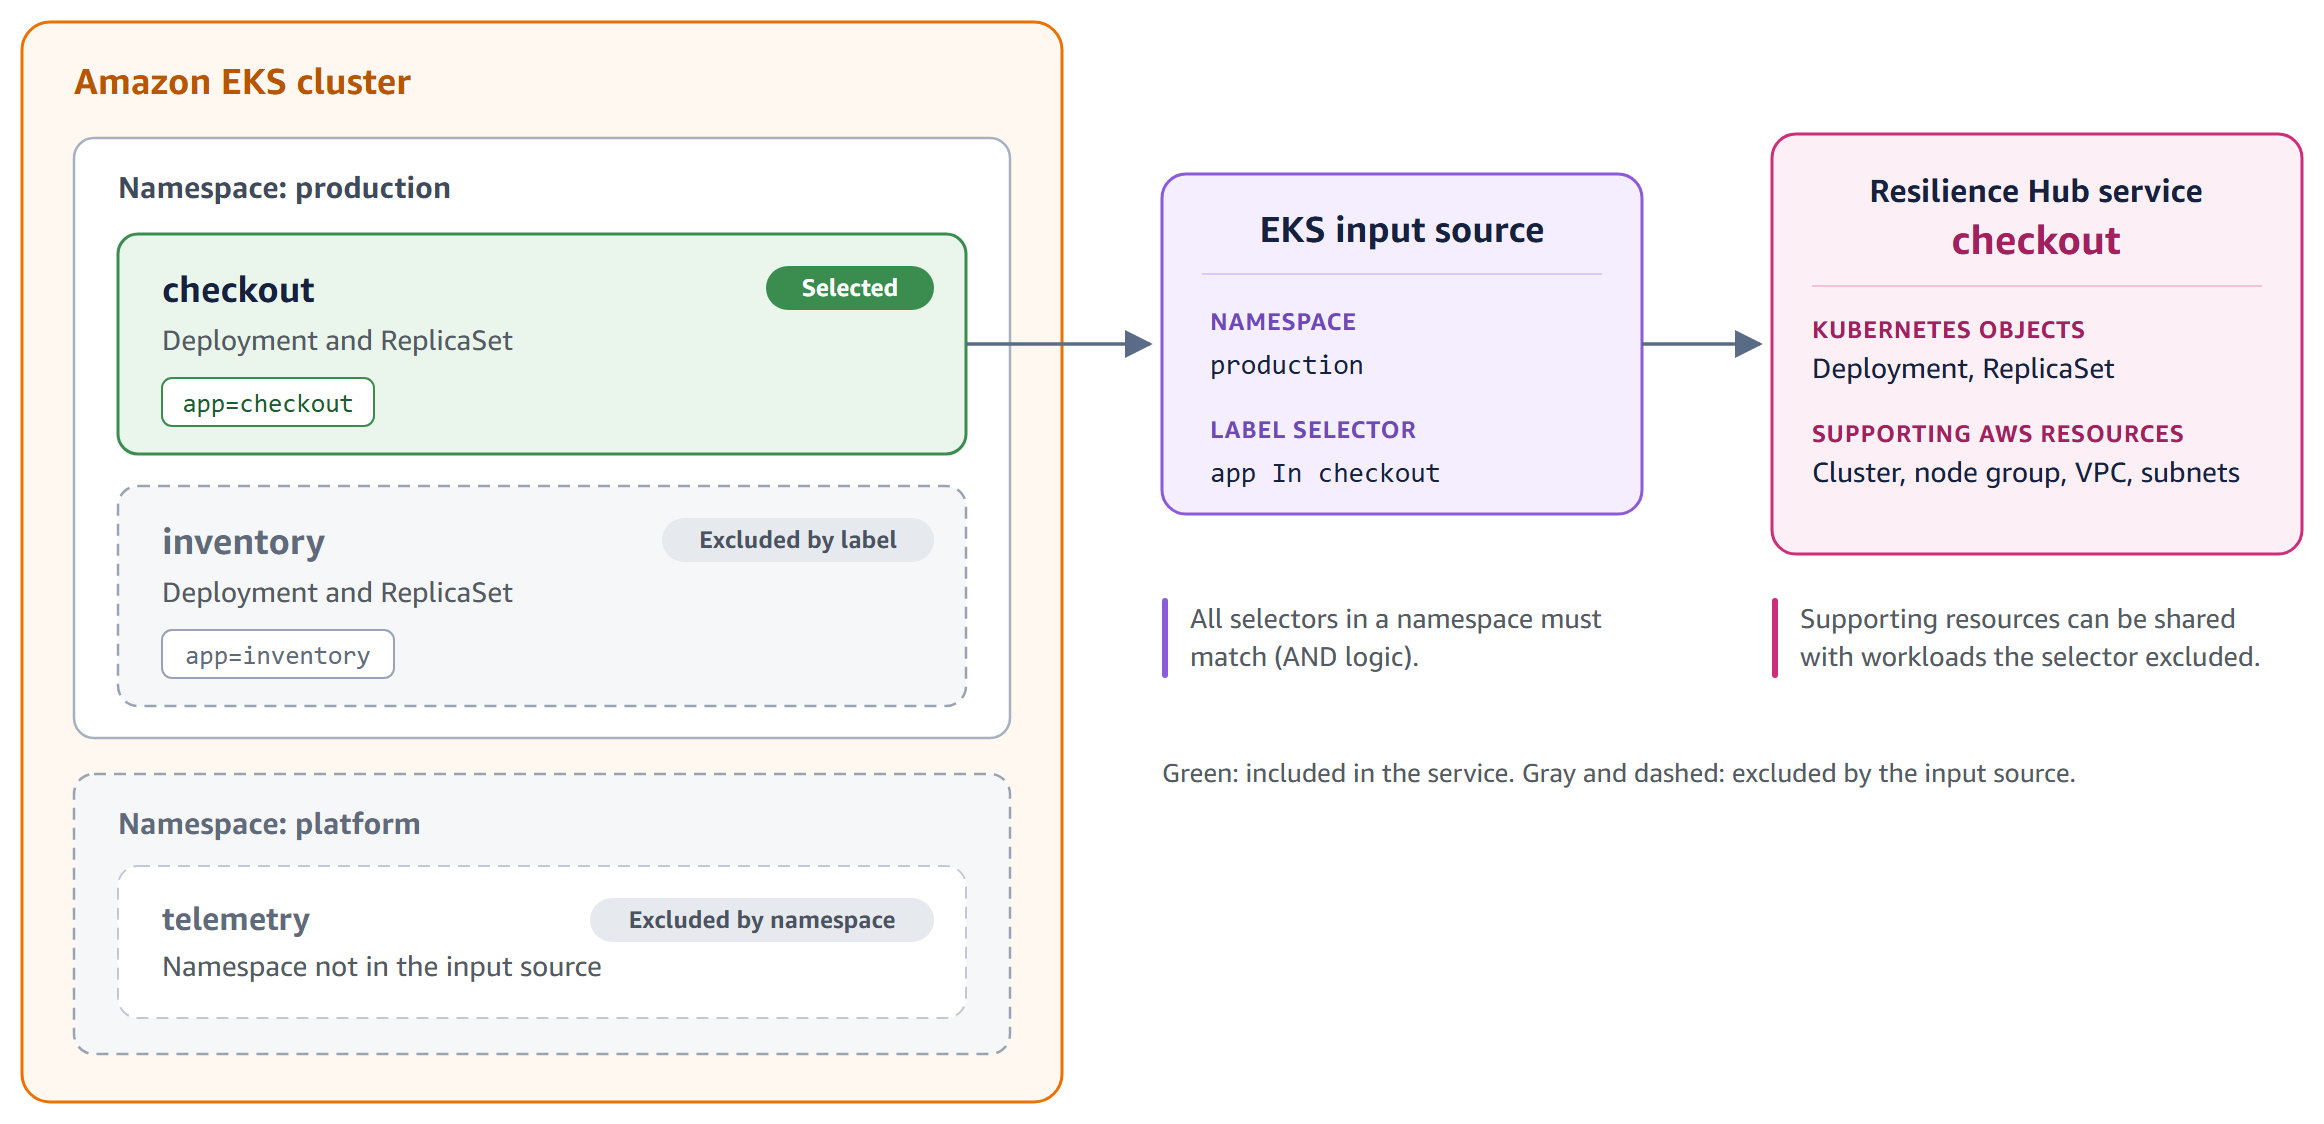
Checkout and inventory share the production namespace. Their resources carry app=checkout and app=inventory, respectively. Selecting production with app In checkout includes checkout’s Deployment and ReplicaSet and excludes inventory.
Figure 1: Selecting checkout resources with a Kubernetes label
The resource list also includes supporting AWS infrastructure, such as the cluster, node group, virtual private cloud (VPC), and subnets. Labels select Kubernetes objects. They don’t make that shared infrastructure exclusive to checkout.
How to use it
In the Resilience Hub console:
Choose Create service and enter a name. Under Permission, choose Create default role to create an IAM role with the required AWS permissions, or choose Use another role to select an existing role.
Under Service resource discovery, choose Amazon EKS cluster and enter the cluster ARN.
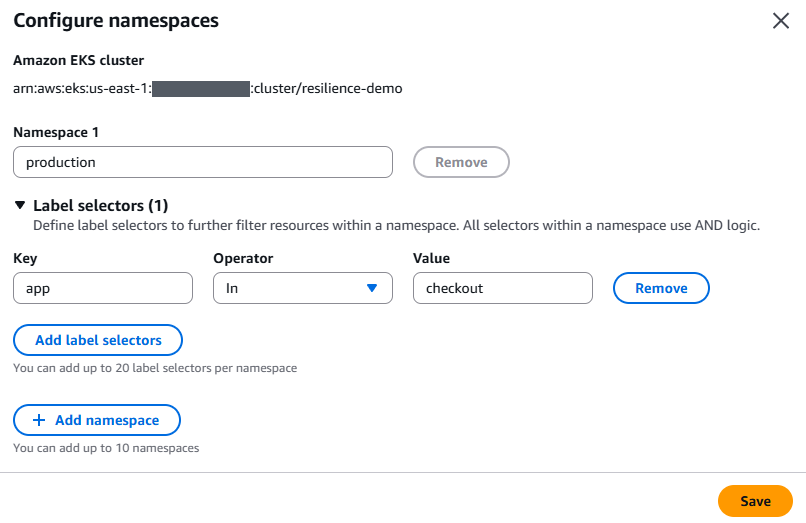
Choose Configure namespaces, enter production, and add a label selector with key app, operator In, and value checkout.
Choose Save, select Enable dependency discovery for this service, then choose Create service. Resource discovery starts automatically.
Figure 2: Scoping the checkout service to one namespace and one label
If you prefer to use the AWS CLI instead of the console, run the following commands to create the service and add its EKS input source.
Skip this block if you already created the service using the preceding console steps.
The console displays selector operators as In, NotIn, Exists, and NotExists. In the API, use IN, NOT_IN, EXISTS, and DOES_NOT_EXIST, respectively.
In the following command, replace ResilienceHubRole with your service’s IAM role name.
# Create the checkout service with dependency discovery enabled and save its ARN
SERVICE_ARN=$(aws resiliencehubv2 create-service \
  --profile workload \
  --name checkout \
  --regions "$AWS_REGION" \
  --permission-model '{"invokerRoleName": "ResilienceHubRole"}' \
  --dependency-discovery ENABLED \
  --query 'service.serviceArn' --output text)

# Add the EKS input source, selecting resources labeled app=checkout in production
aws resiliencehubv2 create-input-source \
  --profile workload \
  --service-arn "$SERVICE_ARN" \
  --resource-configuration '{
    "eks": {
      "clusterArn": "arn:aws:eks:us-east-1:111122223333:cluster/resilience-demo",
      "namespaces": ["production"],
      "labelSelector": {
        "matchExpressions": [
          {"key": "app", "operator": "IN", "values": ["checkout"]}
        ]
      }
    }
  }'
After resource discovery completes, you can use the following command to list the discovered resource types. If you created the service on the console, first set SERVICE_ARN to that service’s ARN.
Dependency Insights uses generative AI to summarize discovered dependencies and highlight patterns that warrant resilience review. It provides an overview and categorized findings.
The Resources list describes the service’s components. The Dependencies list shows endpoints discovered through DNS activity, including AWS service endpoints in other Regions and external APIs. When that list grows to hundreds of entries, Dependency Insights helps you prioritize what to investigate.
How it works
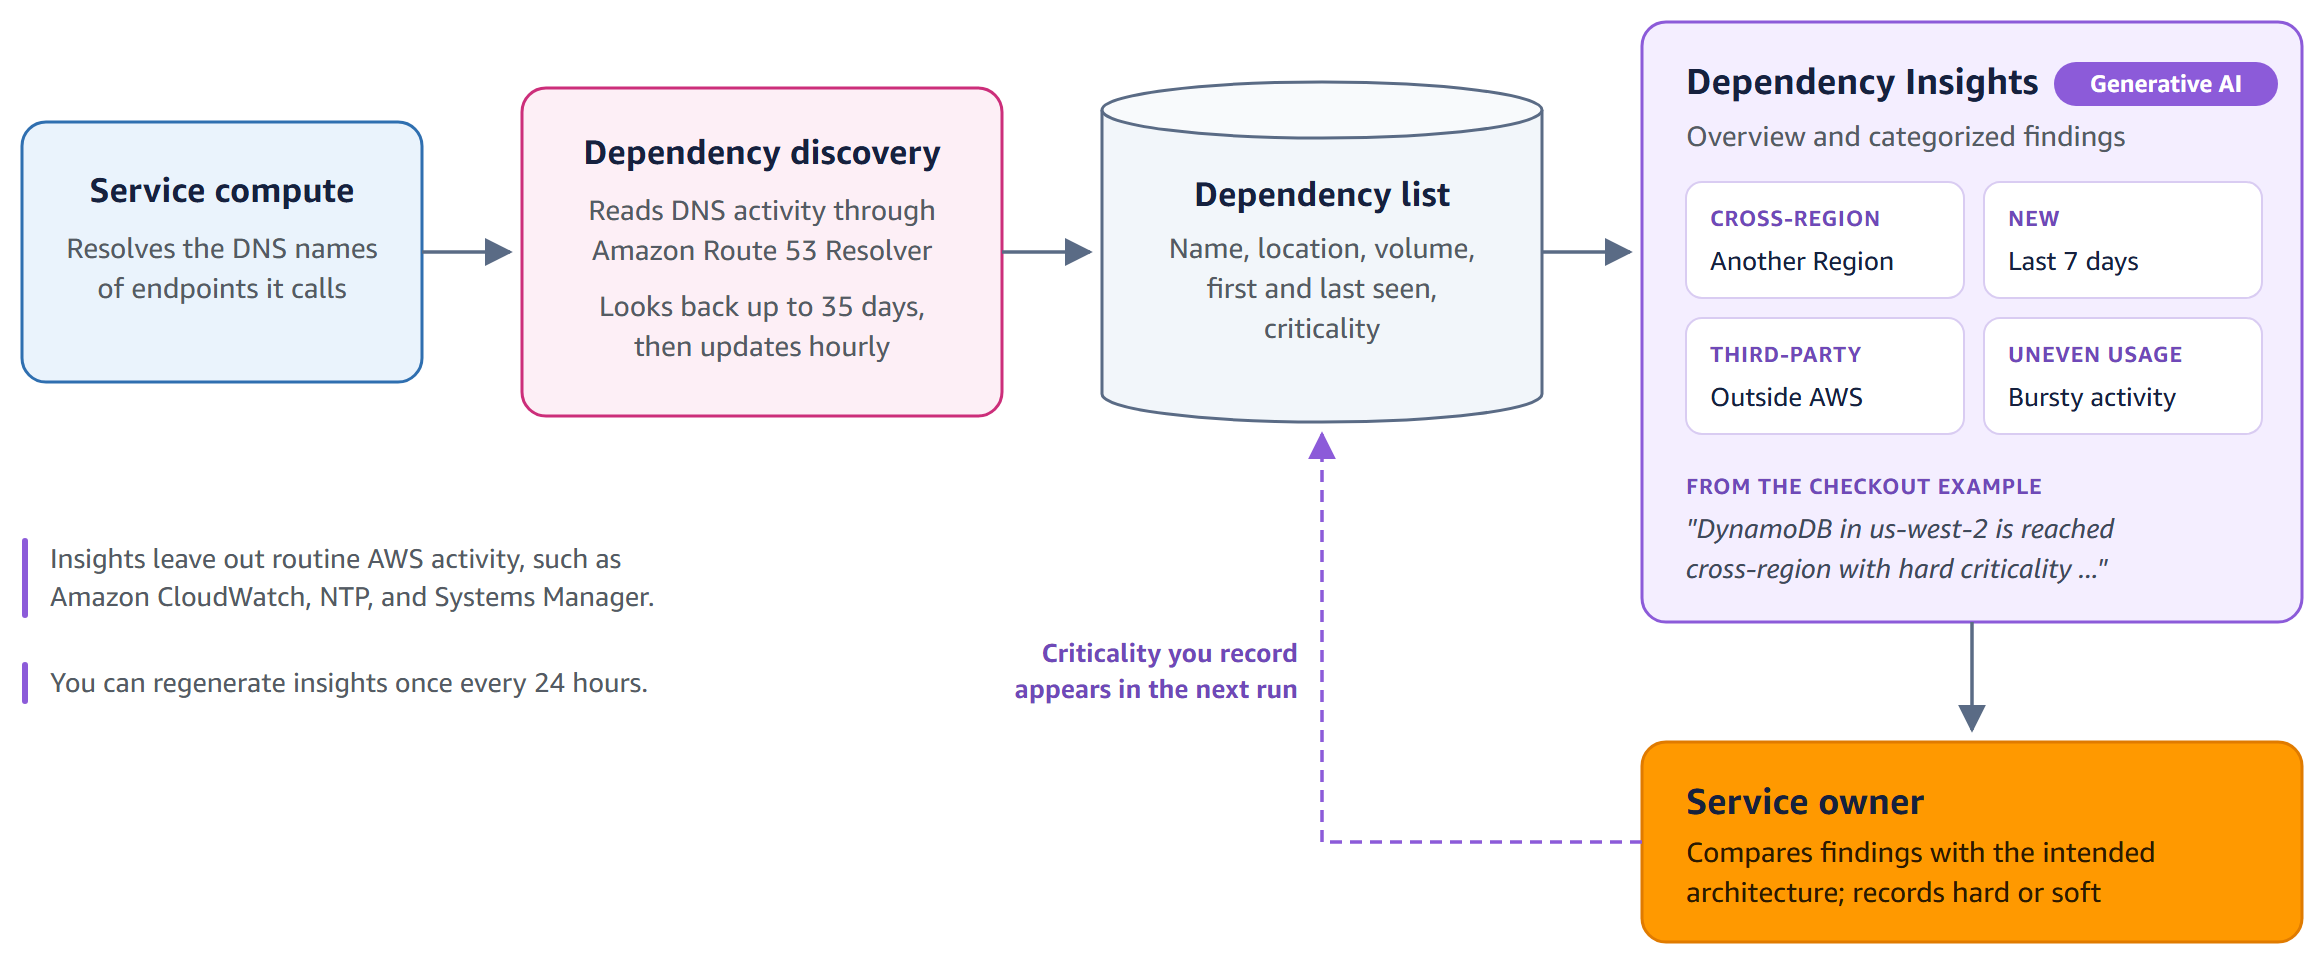
Dependency Insights builds on dependency discovery, an optional, separately priced feature. Dependency discovery analyzes DNS activity through Amazon Route 53 Resolver and does not require installing an agent in your workload. It examines up to 35 days of available history and continues monitoring for changes. The dependency list shows each endpoint’s name, location, and when it was first and last seen.
Dependency Insights analyzes this list, filters out common service activity that typically does not indicate resilience risk, and highlights patterns such as these:
Pattern
What to investigate
Cross-Region dependencies
Whether a call to another Region is intentional, and how it affects recovery
New dependencies
Whether an endpoint first observed within the last seven days changes the documented architecture
Third-party dependencies
How the service behaves when an external provider is unavailable
Uneven usage
Whether activity reflects a scheduled job or a dependency used only at certain times
Figure 3: Turning dependency data into a focused review
Insights prioritize review. They don’t prescribe fixes or list every dependency. Use the full dependency list when you need detail. A new workload’s insights reflect only the history it has generated.
How to use it
In the Resilience Hub console, wait for initial dependency discovery to complete before generating insights:
Open the service. On the Assessment tab, scroll to the Dependencies section to review discovered dependencies.
Choose Generate insights.
Read the overview and compare each finding with the intended architecture.
You can regenerate insights once every 24 hours. This limit applies whether you generate them through the console or the AWS CLI.
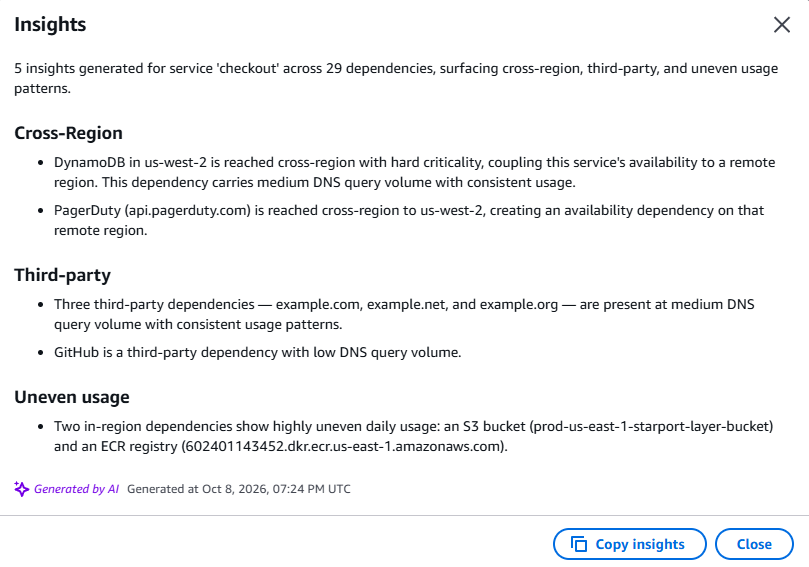
Figure 4: Dependency Insights for the checkout service
If you prefer the AWS CLI, use the following commands instead of the console steps. Set SERVICE_ARN to your service’s ARN.
Enable dependency discovery only if it is not already enabled. After initial discovery completes, review the dependency list and generate insights. If you already generated insights on the console, skip start-dependency-insights and use get-dependency-insights to retrieve the existing result.
Generation can complete asynchronously. Run get-dependency-insights again if the returned status is IN_PROGRESS.
# Enable dependency discovery if it is not already enabled
aws resiliencehubv2 update-service \
  --profile workload \
  --service-arn "$SERVICE_ARN" \
  --dependency-discovery ENABLED

# Review the dependency list
aws resiliencehubv2 list-dependencies \
  --profile workload \
  --service-arn "$SERVICE_ARN" \
  --query 'dependencySummaries[].[dependencyName, location, dependencyId]' \
  --output table

# Start generating dependency insights
aws resiliencehubv2 start-dependency-insights \
  --profile workload \
  --service-arn "$SERVICE_ARN"

# Retrieve insights; if status is IN_PROGRESS, run this command again later
aws resiliencehubv2 get-dependency-insights \
  --profile workload \
  --service-arn "$SERVICE_ARN"
The checkout service produced five insights across 29 dependencies. The following response shows the generated overview and all five findings:
{
    "overview": "5 insights generated for service 'checkout' across 29 dependencies, surfacing cross-region, third-party, and uneven usage patterns.",
    "insights": [
        {
            "category": "CROSS_REGION",
            "description": "DynamoDB in us-west-2 is reached cross-region with hard criticality, coupling this service's availability to a remote region. This dependency carries medium DNS query volume with consistent usage."
        },
        {
            "category": "CROSS_REGION",
            "description": "PagerDuty (api.pagerduty.com) is reached cross-region to us-west-2, creating an availability dependency on that remote region."
        },
        {
            "category": "THIRD_PARTY",
            "description": "Three third-party dependencies — example.com, example.net, and example.org — are present at medium DNS query volume with consistent usage patterns."
        },
        {
            "category": "THIRD_PARTY",
            "description": "GitHub is a third-party dependency with low DNS query volume."
        },
        {
            "category": "UNEVEN_USAGE",
            "description": "Two in-region dependencies show highly uneven daily usage: an S3 bucket (amzn-s3-demo-bucket) and an ECR registry (602401143452.dkr.ecr.us-east-1.amazonaws.com)."
        }
    ],
    "status": "COMPLETED",
    "createdAt": "2026-10-08T14:24:27.372000-05:00"
}
The first finding identifies a cross-Region Amazon DynamoDB dependency. If checkout requires that dependency to accept orders, a disruption in the remote Region could prevent it from operating even when its Amazon EKS resources remain healthy. The service owner should verify which operations require the table and review how those operations behave when it is unavailable. That review determines whether the dependency fits the recovery design or whether the architecture needs to change. DNS activity alone cannot answer that question.
The uneven-usage finding points to container image infrastructure. Image downloads during pod startup can produce bursts of DNS activity. This is a pattern to investigate, rather than evidence that your application has an outage.
Classify a dependency as hard if the service fails without it, or soft if the service degrades but keeps running. In the sample environment, we had classified the DynamoDB dependency as hard using the following command. The comment describes an illustrative failure assumption, which requires validation through testing:
# Classify the selected dependency as hard and record the reason
aws resiliencehubv2 update-dependency \
  --profile workload \
  --service-arn "$SERVICE_ARN" \
  --dependency-id "<dependency-id>" \
  --criticality HARD \
  --comment "Checkout writes orders to this table and cannot accept orders without it."
Resilience policy sharing through AWS Organizations
After reviewing checkout’s dependencies, the service owner can validate its recovery requirements with the business and the central site reliability engineering (SRE) team. Dependency findings inform that discussion. They don’t automatically determine the policy targets.
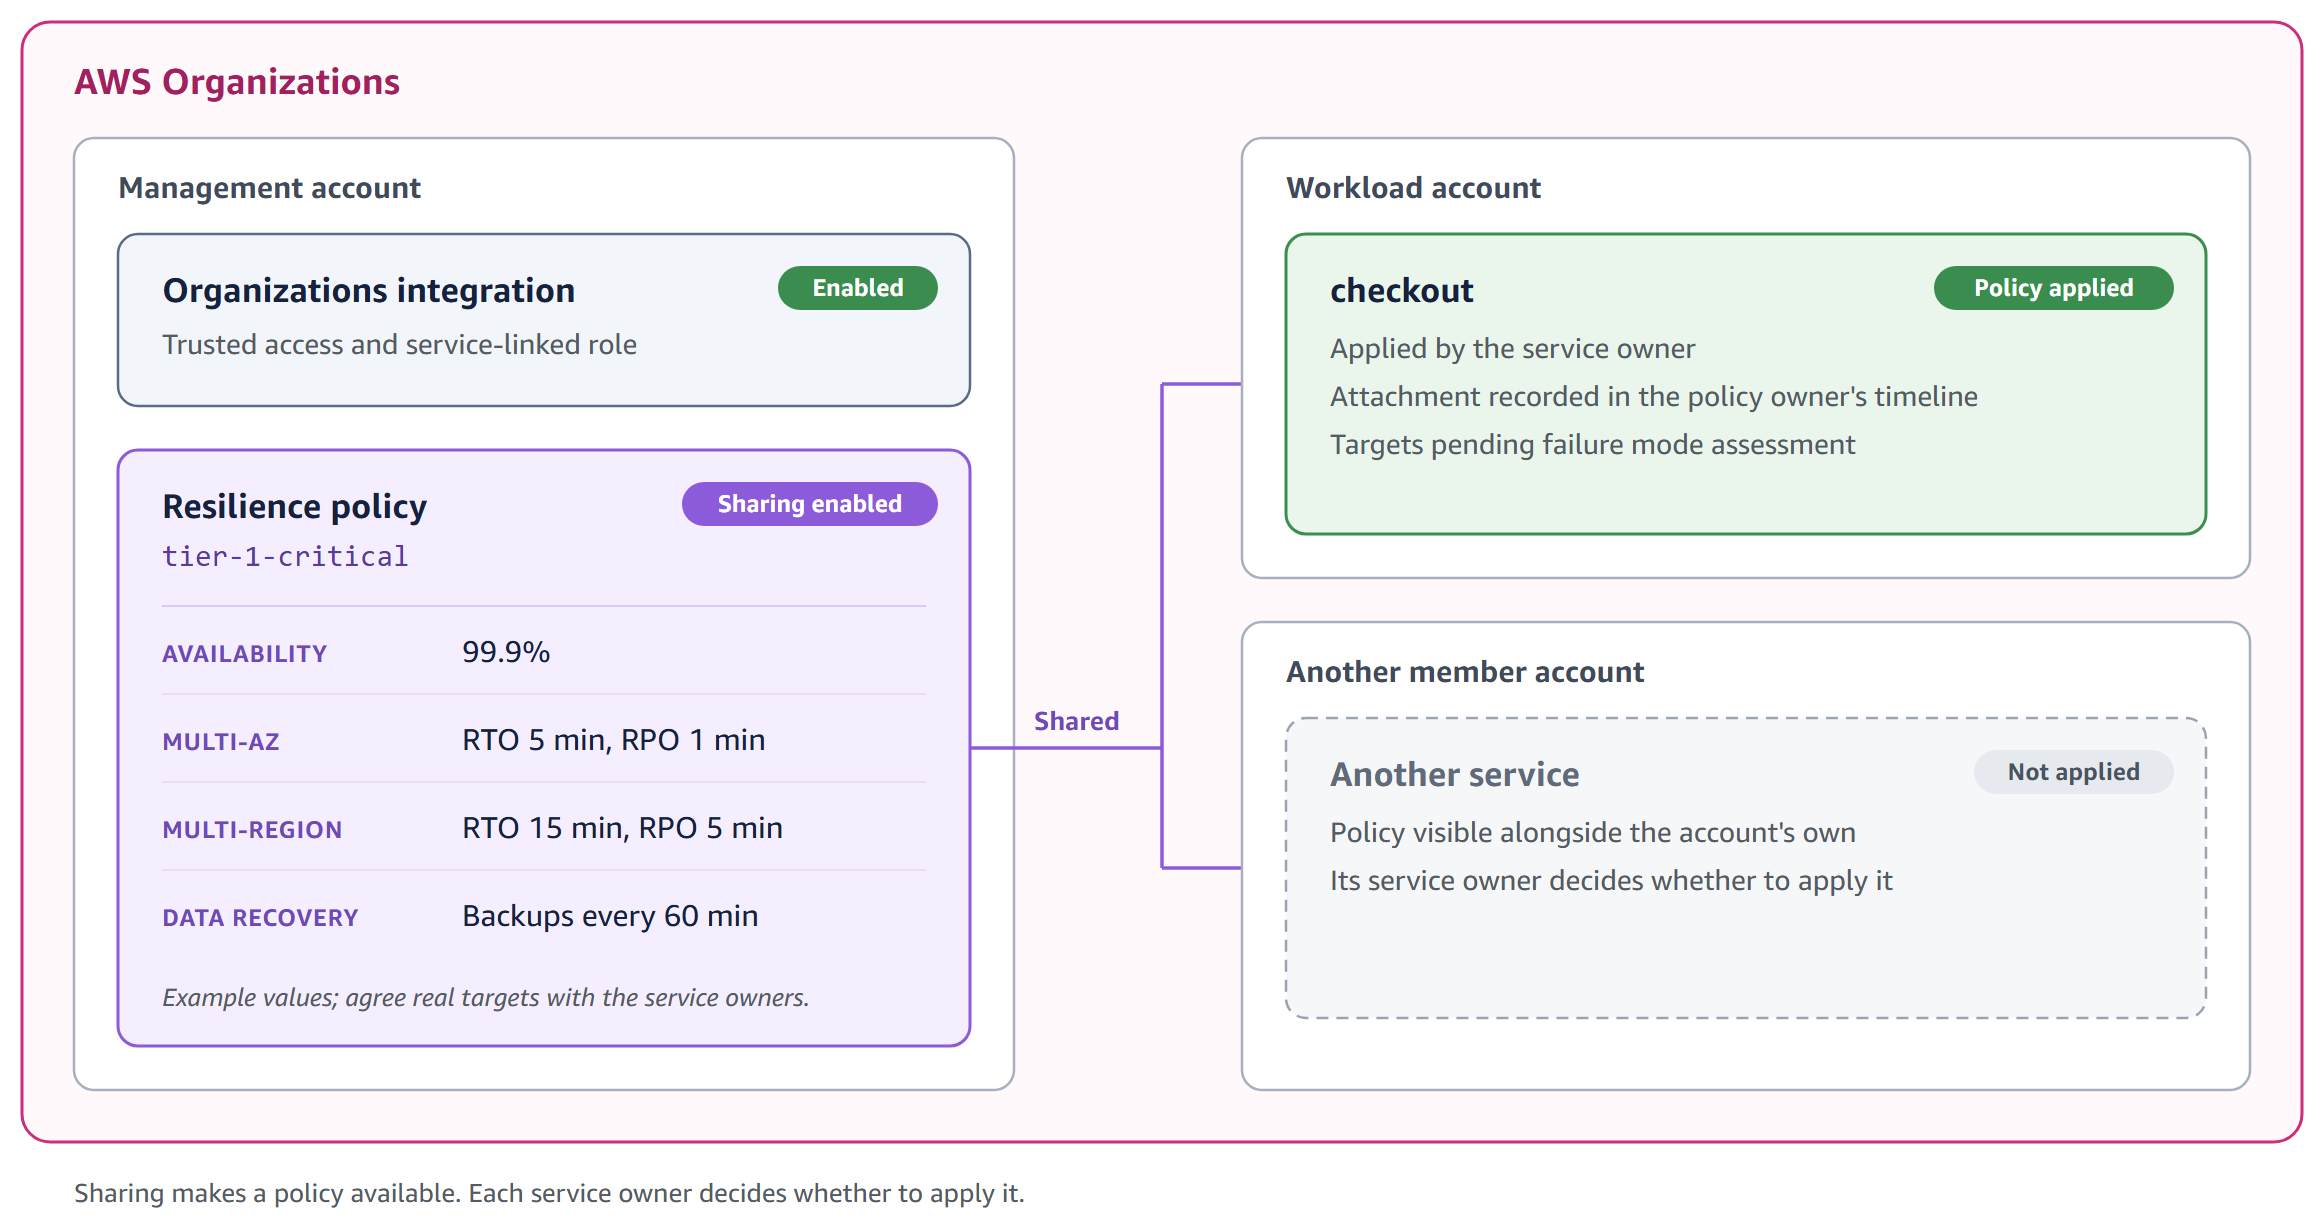
The central SRE team can codify the agreed requirements into a resilience policy, defining availability and recovery targets for critical services. The management account or a delegated administrator can share that policy across the organization so service owners can apply the centrally maintained requirements without creating separate copies.
The policy owner can review attachment and detachment events to track adoption. If a service stops using the policy, the SRE team can engage its owner to understand why and determine whether different requirements are appropriate. Application owners remain responsible for meeting the targets.
How it works
A policy can combine four target types: availability, recovery from an Availability Zone disruption, recovery from a Regional disruption, and data recovery. The recovery time objective (RTO) specifies the targeted recovery time. The recovery point objective (RPO) specifies the tolerable period of data loss.
When sharing is on, the policy appears in every member account alongside the account’s own policies, and its ARN shows which account owns it. Each service owner chooses whether to apply it. If a requirement must apply regardless of that choice, associate the policy with a system containing the relevant services instead, as described in Applying resilience policies across accounts.
The owning account can review a timeline of the services that start or stop using the policy. Turning sharing off stops evaluating member services against the policy and removes it from the services that used it, so coordinate changes with the teams involved.
Figure 5: One policy definition, shared with member accounts
How to use it
The organization integration is a one-time setup in the management account:
In the Resilience Hub console, open AWS Organizations settings.
Select Enable trusted access and create a service-linked role, then choose Create integration.
To confirm that the service-linked role exists in a member account:
# Confirm the service-linked role exists in the workload account
aws iam get-role \
  --profile workload \
  --role-name AWSServiceRoleForResilienceHub \
  --query 'Role.Arn'
Next, create the policy in the management account with sharing turned on. Policy names can contain letters, numbers, hyphens, and underscores, but no spaces. The following targets are examples. Agree on real values with the business and service owners. This example uses an availability target of 99.9 percent.
In the workload account, find the shared policy and apply it to the service. On the console, choose Change policy on the service and select the shared policy. With the AWS CLI:
# List policies available in the workload account, including shared policies
aws resiliencehubv2 list-policies \
  --profile workload \
  --query 'policySummaries[].[name, policyArn, sharingEnabled]' \
  --output table

# Apply the shared resilience policy to the checkout service
aws resiliencehubv2 update-service \
  --profile workload \
  --service-arn "$SERVICE_ARN" \
  --policy-arn "<shared-policy-arn>"
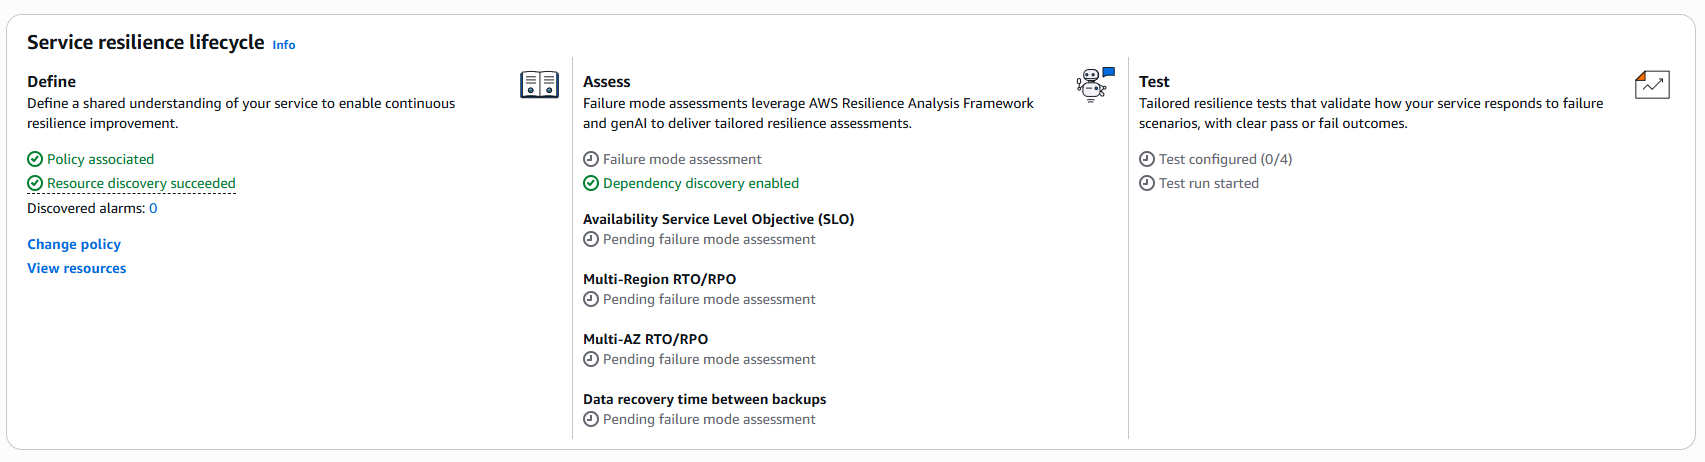
Figure 6: Policy targets are defined. Assessment of those targets is still pending
Back in the management account, the policy owner can confirm adoption:
# Review service attachment events for the shared policy
aws resiliencehubv2 list-policy-events \
  --profile management \
  --policy-arn "$POLICY_ARN" \
  --event-types POLICY_ATTACHED_TO_SERVICE
An attachment event confirms adoption, not compliance. After we applied the shared policy, the console changed each target from Not defined in policy to Pending failure mode assessment. A failure mode assessment and appropriate resilience testing are needed to determine whether the service meets those targets.
Things to know
Shared clusters. Labels decide which Kubernetes objects belong to a service. On a cluster that several workloads share, review the discovered dependencies to confirm they belong to the service, as described in the guidance for shared EKS clusters.
What DNS-based discovery can’t see. Connections made directly by IP address aren’t discovered, AWS Lambda functions need VPC connectivity to be covered, and very infrequent calls might not appear in initial results. See Coverage and known limitations.
Timing. Results reflect the history available to the service. Give a new workload time to build history before drawing conclusions from its insights. You can regenerate insights once every 24 hours.
Cleanup
If you created resources to try these capabilities, remove them when you finish. Turning sharing off also removes the policy from every member service that uses it, so only do this for a demonstration policy:
# Stop sharing the demo policy; this also removes it from member services
aws resiliencehubv2 update-policy --profile management --policy-arn "$POLICY_ARN" --no-sharing-enabled
# Delete the demo policy
aws resiliencehubv2 delete-policy --profile management --policy-arn "$POLICY_ARN"
# Delete the demo Resilience Hub service
aws resiliencehubv2 delete-service --profile workload --service-arn "$SERVICE_ARN"
Delete the EKS cluster as well if you created it only for this walkthrough.
Conclusion
Start with a service whose architecture and ownership you know. Use EKS labels to check its Kubernetes resource boundary, then review Dependency Insights against its intended behavior. If several teams maintain the same requirements separately, consider a shared policy.
You can use the capabilities together or independently. Label support applies to EKS workloads. Dependency Insights and policy sharing also support services beyond EKS. Insights focus the investigation. Your architecture review determines what to change.
In Getting started with Apache Iceberg write support in Amazon Redshift – Part 1, you learned how to create Apache Iceberg tables and write to them with INSERT. In Part 2, you modified data at the row level with DELETE, UPDATE, and MERGE. Both posts assumed your write had the table to itself. In production, that is rarely true: streaming jobs, scheduled pipelines, and one-time transformations frequently write to the same table at the same time. Amazon Redshift now resolves many of these concurrent writes automatically, committing changes that previously failed and were forced to retry. In this post, we explain why concurrent writes to Iceberg tables conflict, how Amazon Redshift resolves the conflicts that don’t actually overlap, how the engine escalates its checks from operations to partitions to individual files, and the throughput improvement it provides.
The challenge of concurrent writes
Apache Iceberg uses optimistic concurrency control (OCC) to keep a table consistent when more than one writer commits at the same time. Each writer prepares its changes against the table’s current version and commits by atomically advancing the table version in the catalog, on the condition that no other writer advanced it first. If another writer commits in the meantime, the condition fails and the entire write is discarded. This strictness maintains snapshot isolation semantics: if the later commit were applied anyway, it would replace the table version without the earlier writer’s changes, silently losing a committed write.
Readers don’t encounter this problem. An Iceberg scan always reads a committed snapshot, so a read is never invalidated by a concurrent write. That leaves write-write conflicts as the only case the engine must resolve, and resolving them correctly is what preserves snapshot isolation semantics for the table.
The problem is the bluntness of this check. The condition is evaluated against the table version, not against the rows or partitions each writer touched. At that grain, its answer is correct in that the version really did change. However, it says nothing about whether the two writes overlapped in the data underneath. Two writers that modified entirely separate partitions, or that independently inserted new data, conflict exactly as hard as two that rewrote the same rows. This happens whenever their query-start-to-commit windows overlap.
Consider a retail analytics platform with a customer_orders Iceberg table. A streaming pipeline might land new orders continuously with hundreds of inserts a minute. A nightly compliance job deletes records older than seven years, and takes about an hour to run. The two writes never touch the same data: the stream only adds recent orders, and the compliance job only removes old ones. Under basic optimistic concurrency, that doesn’t matter. If a single streaming insert commits at any point during that hour, the compliance job loses the race, its hour of work is discarded, and the next attempt re-scans terabytes of data only to re-enter the same race. The table version conflict was real even though the data conflict was not.
The common ways to avoid this are all manual, and each carries a cost. You can serialize your writers so that only one commits at a time, which gives up concurrency entirely. You can split a single logical table into several physical tables so that no two writers ever share one. This trades a clean data model and the ability to query across them for the ability to write in parallel. Or you can wrap every write in an application-side retry loop and absorb the cost of re-running statements that never actually conflicted. In each case, the effort goes toward working around the commit protocol rather than toward your data.
How Amazon Redshift resolves write conflicts
When a commit loses the race, Amazon Redshift now asks a more precise question before giving up: Did the writers that committed ahead of it actually change the same partitions or files or rows it changed? When the answer is no, there’s no reason to discard the work. Instead of aborting, Amazon Redshift rebases the change (similar to git rebase), replaying the already-prepared write onto the latest version of the table and committing that result. Both writes land, with no re-scan, no re-execution, and no retry loop in your application.
In the retail example, the compliance delete previously failed the moment a streaming insert committed inside its execution window. Now Amazon Redshift examines both writes, sees that the inserts only added data files while the delete only removed others, and confirms they never touched the same data. Because the changes are provably independent, Amazon Redshift rebases the delete onto the updated table version and commits it. Both writes succeed, the hour of work is preserved, and downstream consumers see both changes.
This behavior is automatic for eligible writes, with no clustering keys to choose, no repartitioning, and no setting to enable. When two writes genuinely conflict, the behavior is unchanged from today: the conflict surfaces and the later writer fails and must retry.
Two principles govern how the resolution works. The first is that a conflict is a matter of granularity. A failed race isn’t automatically a conflict. It’s a question that can be asked at different resolutions. The engine can ask whether any writer removed data at all or whether they only added it, and if data was removed, whether it came from the same partition, the same file, or the same rows that the current write touched. The finer the granularity examined, the more apparent conflicts turn out to be independent changes that can safely coexist. But finer checks also cost more: taken to the limit, the engine could intersect two change sets row by row, and that is expensive and usually unnecessary. So Amazon Redshift evaluates the least expensive level first and examines a finer level only when it must.
The second principle is that correctness takes precedence over concurrency. Conflict resolution works entirely from table metadata and never re-scans data or re-plans a query. When the engine can’t prove that two writes are independent, it doesn’t guess. It declines to resolve the conflict and the write retries, exactly as it would today. An unnecessary retry costs a small amount of time, whereas an incorrect resolution risks losing data, so the system is deliberately biased toward the safe outcome. Resolution operates under snapshot isolation, the same model Amazon Redshift already uses for Iceberg reads. Engines such as Apache Spark, Amazon EMR, and Amazon Athena honor it through the table’s isolation-level property, so a table shared across engines retains consistent semantics. For tables whose write isolation property is set to serializable, Amazon Redshift preserves the stricter contract and surfaces every conflict rather than resolving it. This is the Iceberg table property write.*.isolation-level. It’s unrelated to the Amazon Redshift database isolation level set with ALTER DATABASE … ISOLATION LEVEL, which governs Amazon Redshift transactions and has no effect on Iceberg commit conflict resolution.
Resolving at the right granularity
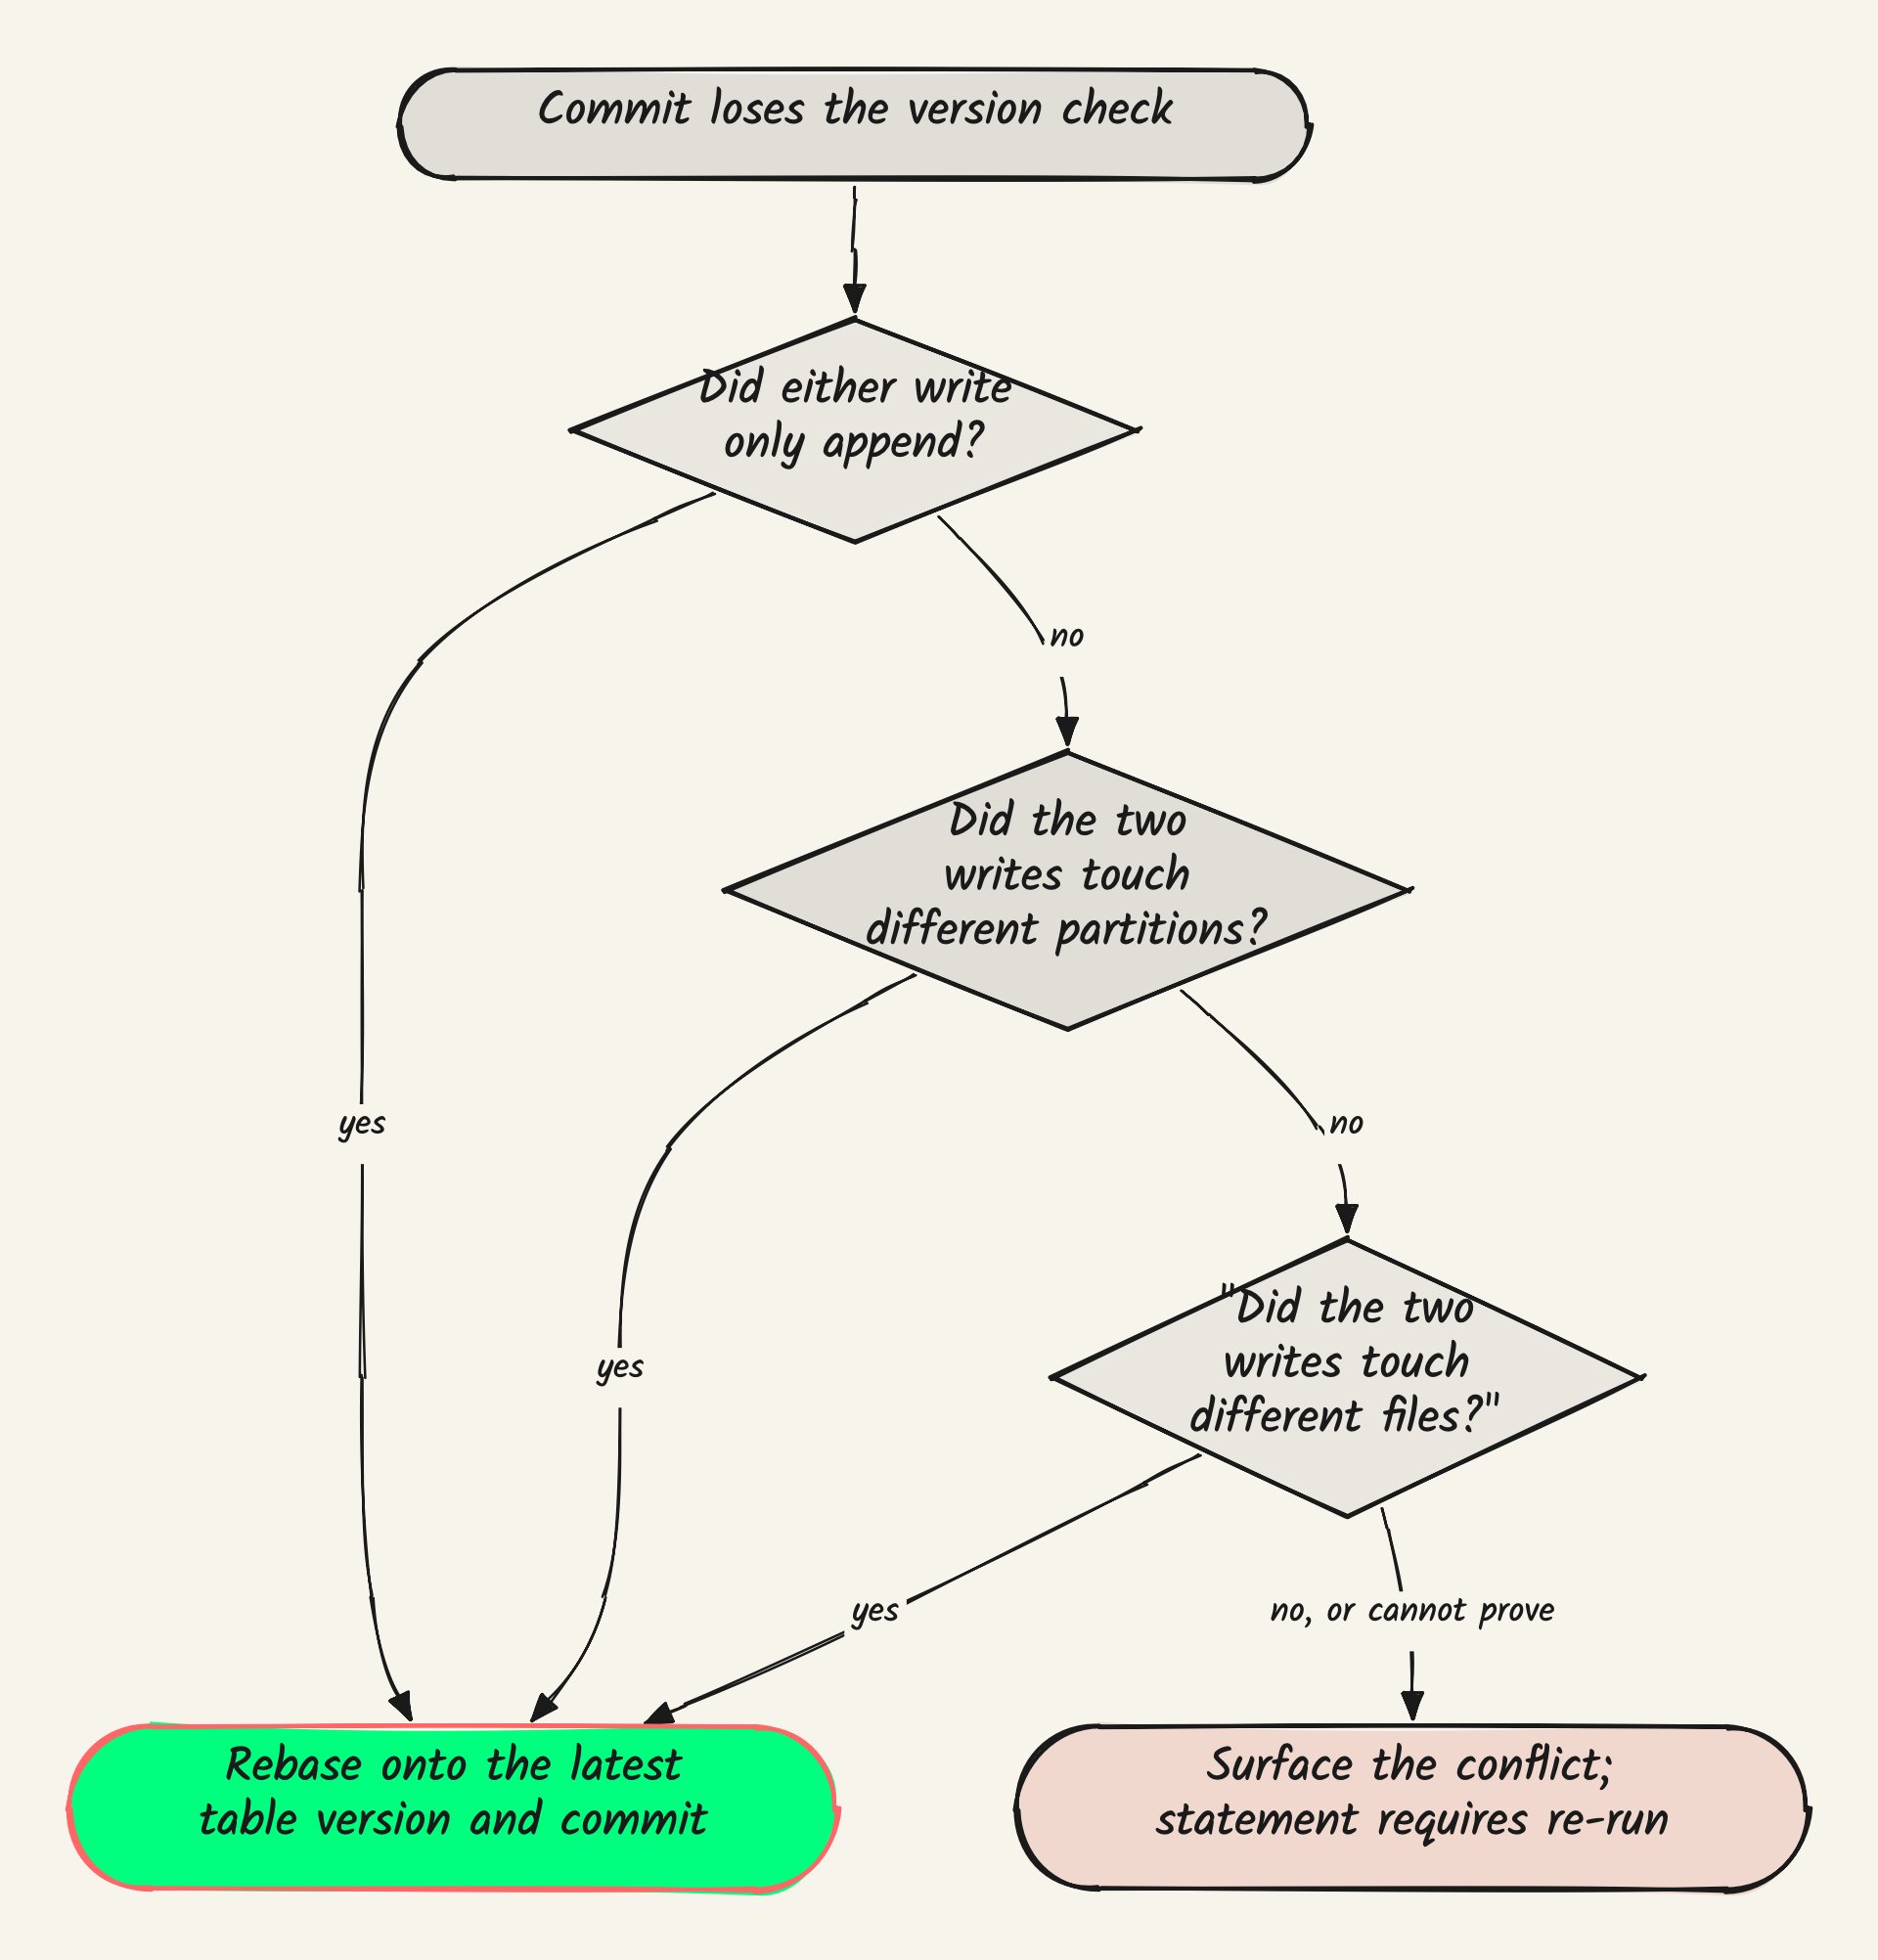
When a commit loses the race, the engine escalates through a sequence of checks, from the cheapest to the most precise. Each level is a complete resolution on its own and if a check proves the writes independent, the rebase commits and no finer check runs. The following diagram shows this escalation sequence: an operation-level check first, then partition-level, then file-level. Each level either proves the writes independent or escalates to the next, and a genuine conflict surfaces only after the last.
Figure 1: The conflict-resolution escalation from operation-level to partition-level to file-level checks
The first check is by operation. A write that only added data, for example an INSERT consisting of new data landing from a streaming job, can’t have removed anything another writer relied on, so any write can be rebased against it. This single rule resolves every combination in which at least one of the two writes only appended. A DELETE, UPDATE, or MERGE commits cleanly against a stream of concurrent inserts, and an INSERT commits cleanly over any other concurrent change, including a compaction.
Next, when both writes removed data, the engine compares the partitions they each touched. Writes that modified disjoint partitions, for example batch jobs updating different dates or per-Region pipelines maintaining their own slices of one table, are independent by construction and both can commit cleanly.
Finally, when both writes touch the same partition, the engine compares the individual files that each one changed. Two jobs deleting different rows of the same date partition usually land in different files, and when they do, both can commit cleanly. Only when two writes modified the same file does the conflict surface and the statement re-run. The protocol additionally has headroom for one further level: distinguishing changes to different rows within a single file.
The following table summarizes the outcomes by operation pair. Read down for the concurrent write that committed first, and across for your write.
Your write ↓ / Concurrent write →
INSERT
DELETE / UPDATE / MERGE
Compaction
ALTER
1
INSERT
Resolves
Resolves
Resolves
Re-run required
2
DELETE / UPDATE / MERGE
Resolves
Resolves based on partitions or files touched. A same-file change surfaces as a conflict
Resolves based on partitions or files touched. A same-file change surfaces as a conflict
Re-run required
3
ALTER
Re-run required
Re-run required
Re-run required
Re-run required
Performance
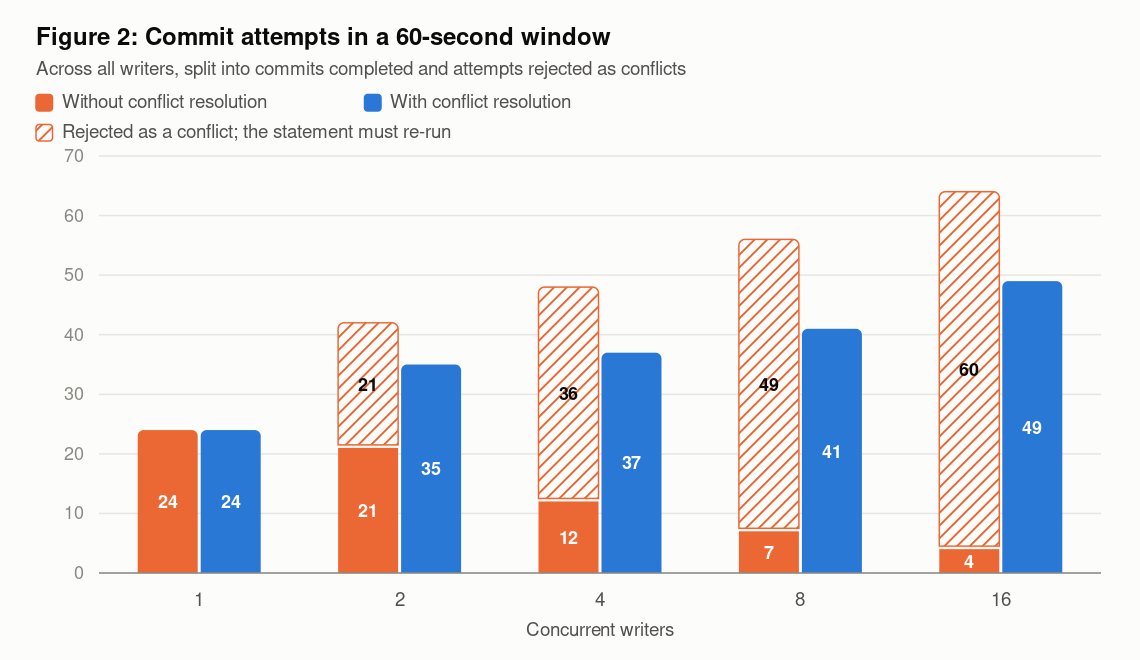
To measure the effect, we ran an increasing number of concurrent writers committing to a single Iceberg table over a fixed window. We compared basic optimistic concurrency mode, where a losing commit is aborted and re-runs, against automatic conflict resolution mode being enabled. Every writer issued the same single-statement INSERT, so the only variable across the various runs was contention rather than workload. We scaled 1–16 concurrent writers and recorded, for each configuration, how many commits succeeded and how many were rejected as conflicts.
Setup: one unpartitioned Iceberg table registered in the AWS Glue Data Catalog in the US East (N. Virginia) AWS Region (us-east-1). Each writer is an independent session issuing autocommit INSERT statements in a loop over a 60-second period. We report the commits completed and the attempts rejected as conflicts for each configuration.
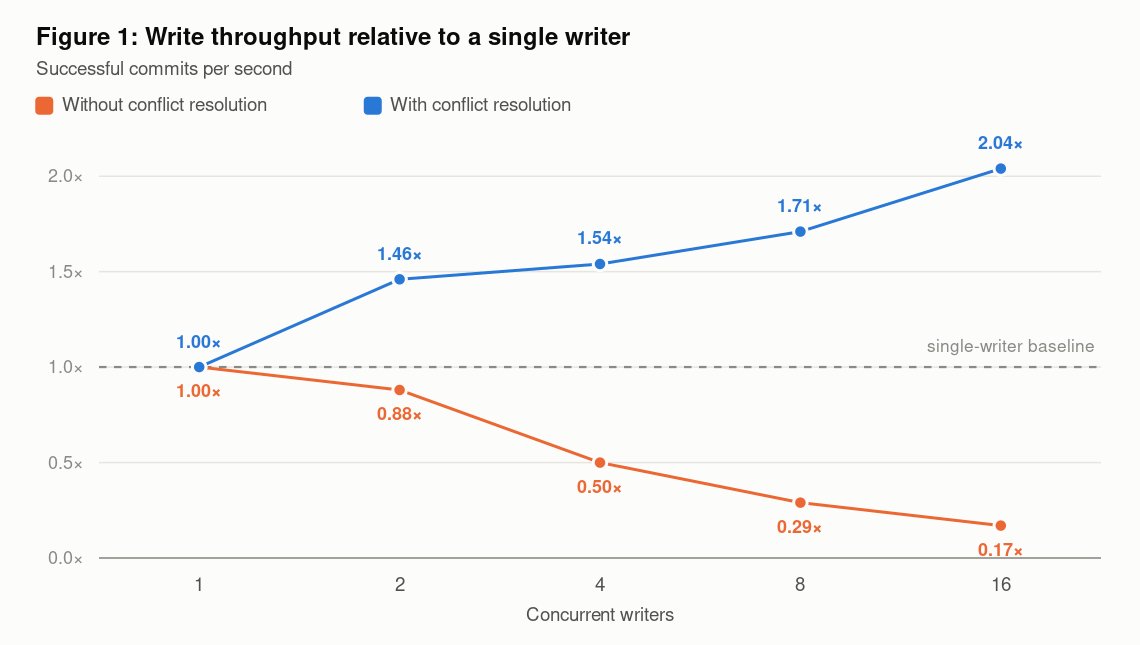
The first figure shows write throughput as writers are added, normalized to the single-writer case so the comparison doesn’t depend on instance type or table size.
Figure 2: Write throughput as concurrent writers increase, with and without automatic conflict resolution
Under basic optimistic concurrency, adding writers makes writing to the table slower. At 16 writers, throughput falls to 0.17× of a single writer, because nearly every writer’s work is discarded and redone rather than committed. With automatic conflict resolution the same workload scales to roughly 2×, and no commit is rejected in any measured configuration. At 16 concurrent writers, 12× more commits complete in the same window. The second figure shows why.
Figure 3: Commit failure rate as concurrent writers increase, with and without automatic conflict resolution
The baseline’s failure rate is almost exactly (N−1)/N, for example 50 percent at two writers, 75 percent at four writers, and 94 percent at 16 writers. This illustrates the table-level check that occurred previously: only one writer wins each commit round and every other writer in flight is rejected. Additional writers translate almost entirely into repeated work rather than progress. With conflict resolution enabled, the same runs record no conflicts at all, because every write in this workload is an append, and an append never removes data another writer relied on.
This benchmark isolates the most basic append case deliberately: a single unpartitioned table and insert-only writers, which is the pattern behind continuous ingestion. Workloads that remove data exercise the partition and file checks described earlier, where the outcome depends on whether the two writes touched the same partition and the same files.
Fleet Results
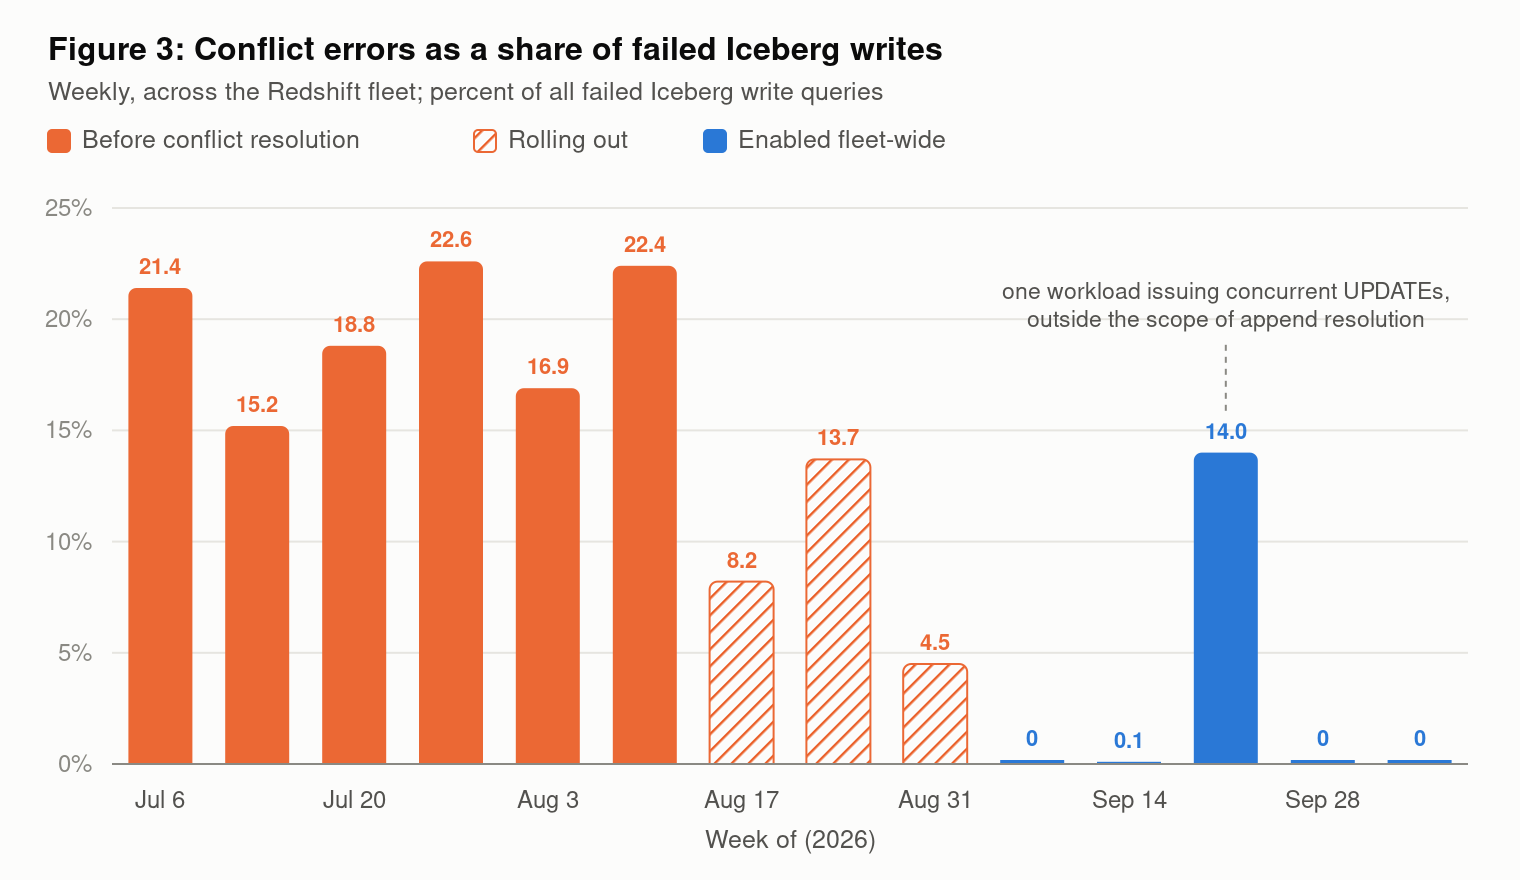
Before conflict resolution, concurrent-write conflicts were the single largest cause of failed Iceberg writes in Amazon Redshift, accounting for roughly one in five failed Iceberg write queries each week. We rolled out this feature in stages, beginning with the operation-level check that covers concurrent appends. As that stage reached full fleet deployment in early September 2026, conflict errors from concurrent writes dropped to nearly zero, even as Iceberg write volume on the fleet more than doubled. One residual spike shown below came from a workload issuing concurrent UPDATE statements, a conflict class that subsequent partition and file level checks will resolve as they deploy across the fleet.
Figure 3: Conflict errors as a share of failed Iceberg writes
Observing conflict resolution
Every Iceberg commit attempt is recorded in the stl_iceberg_commit system table, including the outcome, the number of attempts, the concurrent operations the write rebased over, and the time spent rebasing. To see how often resolution is engaging on an example table:
SELECT outcome, count(*), avg(attempt_number)
FROM stl_iceberg_commit
WHERE trim(table_name) = 'customer_orders'
GROUP BY outcome;
Conclusion
Concurrent writes are a fact of production data lakes, and until now, they forced you to serialize writers, partition around the problem, or retry. With automatic conflict resolution, Amazon Redshift commits concurrent writes that don’t actually overlap. These include any mix of writes alongside concurrent appends, and row-level writes that changed different partitions or different files of the same table. To get started, write to your Iceberg tables from multiple jobs on patch 203 or later. Non-conflicting commits start to resolve on their own. To learn more about Iceberg write support in Amazon Redshift, see Part 1 and Part 2.
You can now run a standard Node.js web server on AWS Lambda with Lambda Web Functions, a new type of Lambda function. Deploy it with one command or AWS CloudFormation and get a public HTTPS endpoint with no adapter layer and no servers or load balancers to manage.
Lambda Web Functions suit server-side rendered web apps, REST and GraphQL APIs, streaming endpoints, and microservices. Building on the launch announcement, this post uses a sample application to show how one execution environment handles many requests at once and how the same app serves a global audience. See how active-CPU billing keeps the cost of waiting low while your code waits, with memory and requests billed separately.
Overview
Lambda launched in 2014 with a minimal model: upload your code, and the service handles everything else. For over a decade that code ran as an event handler, invoked once per event such as a batch of queue messages or an object landing in Amazon Simple Storage Service (Amazon S3). We now call this an Event Function and it remains the right choice for event-driven work.
Web Functions are a second type of Lambda function, running on the same Firecracker-based isolation as Event Functions. Instead of a handler that receives an event, your code runs as a standard HTTP server that listens on a port, which is what lets a web framework, or in this case a plain Node.js server, run unmodified.
A Web Function is made of three resources:
Web Function is the top-level resource with a name and configuration.
Revision is an immutable snapshot of your code and configuration which Lambda creates each time you deploy code or change revision configuration, so you can roll back by routing traffic to an earlier revision.
Endpoint is a network entry point with a unique HTTPS domain, an authentication type, and the rules that route traffic to your revisions.
At launch, Web Functions run Node.js 24 on Arm64, with 2 vCPUs and 2 GB of memory per execution environment. Web Functions support Amazon Virtual Private Cloud (VPC) connectivity, allowing your function to access resources that exist within a VPC.
Walkthrough
Node.js frameworks that start an HTTP server, such as Express, Fastify, and Hono, run without adapters. Next.js in standalone mode needs a small index.js that sets its host and port. This post uses a plain Node.js server to stay dependency-free.
The pattern instructions show how to clone the repo and change to the pattern directory or download the pattern .zip file to run the example.
The app
The dashboard is a single Node.js HTTP server that streams live server metrics to the browser over server-sent events (SSE).
The runtime provides the address to listen on in the AWS_LAMBDA_HTTP_ENDPOINT environment variable, in host:port form. The server reads it and starts listening, exactly as it would anywhere else:
The runtime is nodejs24.x, and it loads index.js at the package root by default. To use a different entry file, set AWS_LAMBDA_NODEJS_ENTRYPOINT to its path.
Run locally
You can run the server locally with npm start.
Browse to http://localhost:3000/ to view the dashboard streaming from the local server.
For this example, you can also use npm run deploy defined in the package.json file.
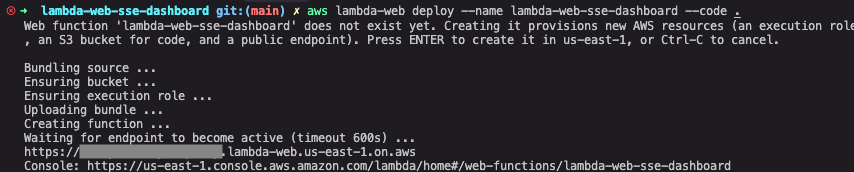
The AWS CLI bundles your code, creates the function and an endpoint named dev with a live HTTPS URL. It also creates an execution role and a versioned S3 bucket, if one does not exist, that all CLI-deployed Web Functions in the Region share.
Press Enter to create the resources.
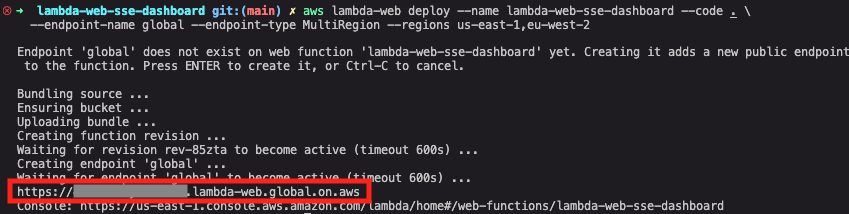
The AWS CLI output shows the URL in the format: https://<id>.<shard>.lambda-web.<region>.on.aws
Figure 1: AWS CLI showing the aws lambda-web deploy command.
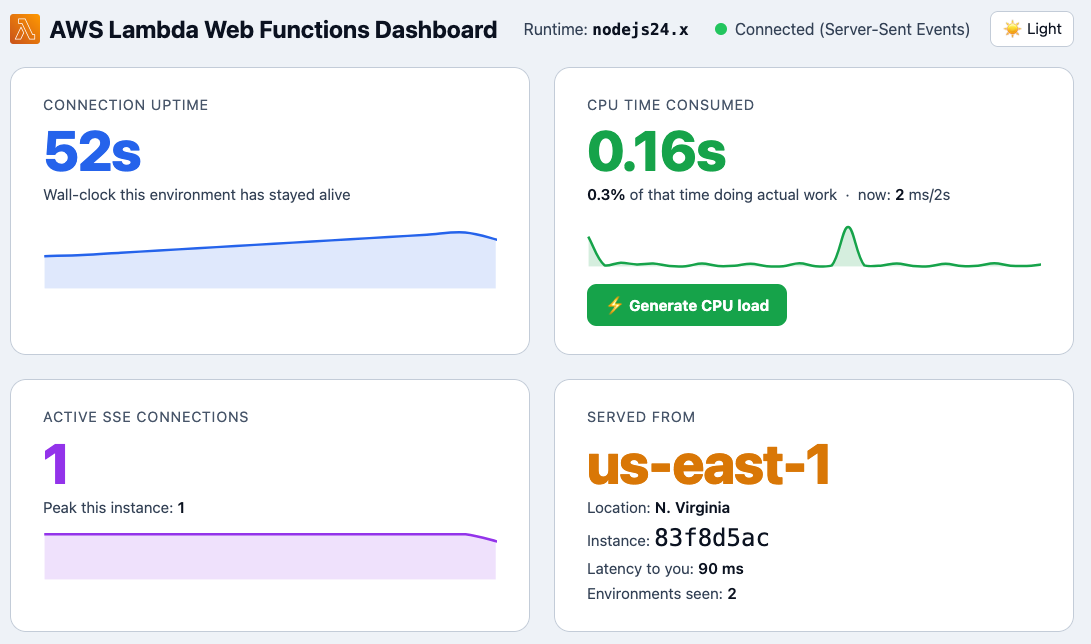
Browse to the URL and the dashboard loads, already streaming. This endpoint is public and the sample has no authentication, so use it for evaluation and delete it when you finish.
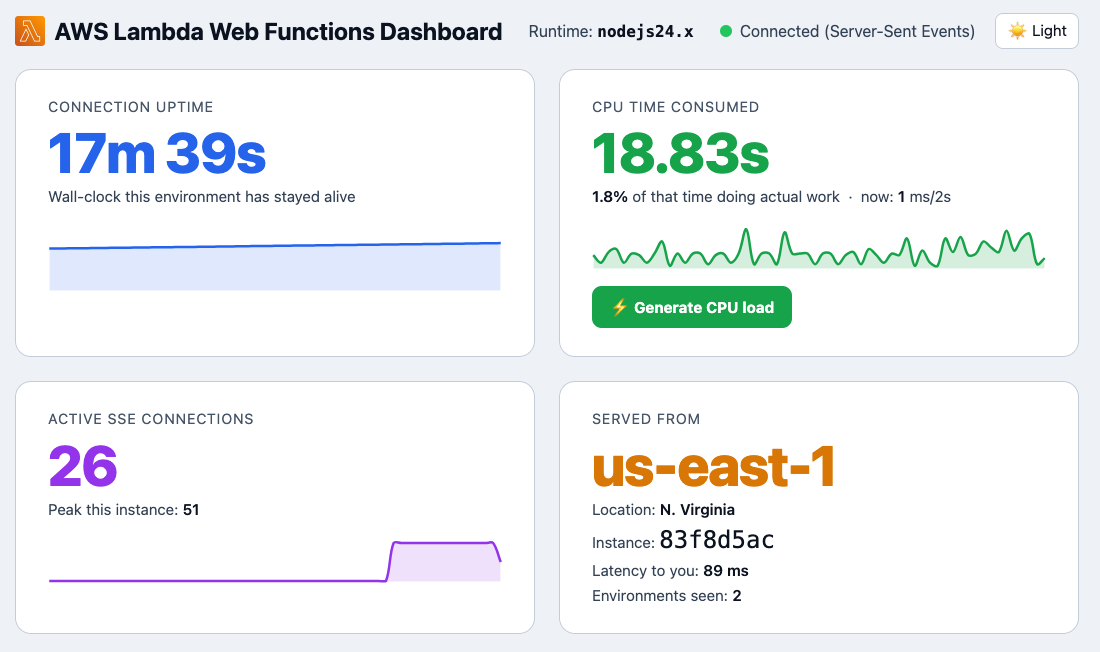
Figure 2: The app streaming dashboard showing function information.
The dashboard shows how long the execution environment has been alive and how many streaming connections it is holding open. It shows how much CPU it has used with a button to generate real CPU load on demand. The function runs in the US East (N. Virginia) Region (us-east-1). From my laptop in the United Kingdom, latency is 90 ms.
The dashboard updates every two seconds over a single HTTP streaming response. A Web Function environment is a long-lived process, so it keeps the connection open and keeps pushing data to the browser. The long-lived process can also run background tasks outside the main request path, such as emitting telemetry events.
An Event Function environment serves one request at a time. It can stream a response during an invocation, but each open stream occupies a whole environment. Lambda freezes the environment between invocations, so background work stops.
Active-CPU billing
If the environment stays alive for minutes at a time, what are you paying for? You pay for requests, consumed memory, and the CPU time the environment consumes. For this example, compare connection uptime with CPU time. The environment keeps running but uses only a fraction of a second of CPU.
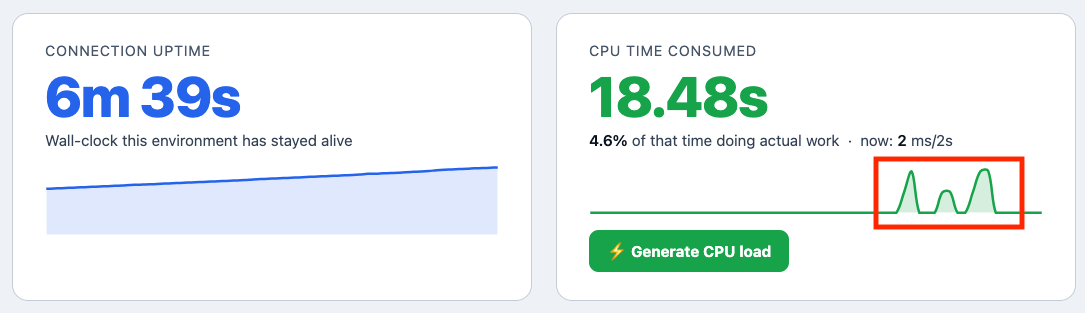
Choose Generate CPU load, and the app runs a cryptographic hashing loop for about 1.5 seconds. CPU time climbs on the chart, then falls back to near zero when the work stops. When a request waits on a database, downstream API, or AI inference, your code uses little CPU, so the wait costs less than it would under wall-clock billing.
Figure 3: CPU chart mid-spike after choosing Generate CPU load.
With Web Functions, each execution environment handles many requests at once, not one at a time. As environments approach their concurrency limit, Lambda adds more environments and removes them again when traffic falls.
You can control how a Web Function scales. maxConcurrencyPerEnvironment sets the maximum number of requests each execution environment handles at once, up to 128, with a default of 64. On the endpoint, maxEnvironments caps the number of execution environments and rateLimit caps requests per second. You can use these two settings to protect downstream dependencies such as databases and external APIs. Both apply in each Region the endpoint serves and maxEnvironments applies to each revision. Requests above a limit receive HTTP 429 and are not queued.
Generate load on the app. Send 300 streaming requests to the /api/events endpoint, with up to 200 open at once, rather than a burst of quick responses.
Figure 4: Concurrency showing increased connections in a single execution environment.
The dashboard updates to reflect the active SSE connections and peak for the currently connected execution environment.
The runtime also writes a per-environment summary record to Amazon CloudWatch Logs every minute with the instance ID, request count, peak concurrency, and CPU time. A CloudWatch Logs Insights query aggregates them across the fleet:
From a sample run of 300 streaming requests with up to 200 open at once, the logs showed the following:
Execution environments used: 5.
Total requests handled: 484.
Peak concurrency on a single environment: 59.
Total CPU consumed across the whole fleet: 4.75 seconds.
One environment peaked at 59 connections, near the default limit of 64. Lambda adds environments before existing ones reach their limit, so this load used five. Event Functions serve one request per environment, so 200 open streams would need up to 200 environments. Across 484 requests, the whole fleet used about 4.8 seconds of CPU.
Each environment reports only its own connections, because Lambda routes each request independently with no session affinity.
Going multi-Region
The same app can serve each caller from the Region with the lowest latency. Because an endpoint’s type and Regions are fixed when you create it, going global means adding a new endpoint:
Lambda replicates your code and revision configuration, including environment variables, to each Region, and centralizes logs in the home Region. In this case, Lambda replicates to Europe (London) Region (eu-west-2). It provides a single global domain URL and uses Amazon Route 53 latency-based routing to send each request to the lowest-latency Region.
Browse to the new global URL which is now in the format: https://<domain>.lambda-web.global.on.aws
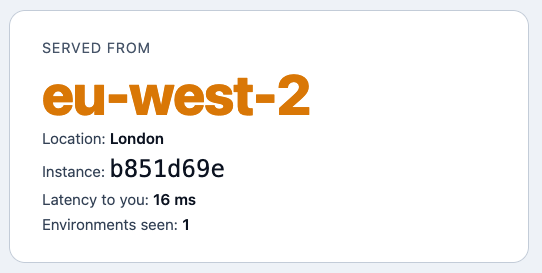
Figure 6: The app dashboard showing routing to the local Region.
From my laptop in the United Kingdom, the request routes to eu-west-2 (London) in 16 ms, where the single-Region endpoint in us-east-1 replied in 90 ms. These are single measurements from one location, not a benchmark. Each request goes to the Region with the lowest latency for the caller through the same URL. Lambda manages the DNS routing, so there are no load balancers or Route 53 records to configure.
Authentication and running behind Amazon CloudFront
Each endpoint has an authentication type that you can change without redeploying code.
With ApplicationManaged, the endpoint is public, and your code handles authentication (OAuth, JWT, a session cookie, or Amazon Cognito). Administrators can prevent public endpoints across an organization with a service control policy that uses the lambda:Request/WebFunctionAuthType condition key.
With IamAuth, Lambda validates each request with AWS Signature Version 4 (SigV4) for single-Region endpoints and SigV4a for multi-Region endpoints. Only callers with the lambda:InvokeWebFunctionEndpoint permission reach your app, which suits service-to-service APIs. Endpoints are always reachable over the public internet, and IamAuth controls who can invoke them.
Endpoints use a Lambda-provided domain. For a custom domain, edge caching, and AWS WAF, place Amazon CloudFront in front of the endpoint. Use IamAuth with origin access control so the Lambda domain cannot bypass CloudFront which still passes your application’s own Authorization header through to your code.
Build it with an agent
Because deployment is a single aws lambda-web deploy command and the code is an ordinary HTTP server, you can scaffold, build, and deploy an app from a prompt using AWS skills for coding agents. The Agent Toolkit for AWS includes Web Functions.
Clean up
To remove the default resources that the aws lambda-web deploy command created, see the cleanup instructions in the repo.
Conclusion
AWS Lambda Web Functions bring the serverless operating model to web applications without adapter layers. You write a standard Node.js HTTP server, deploy it with one command or CloudFormation, and get a scalable, pay-per-use HTTPS endpoint with global routing built in. Deploy the sample application from the Serverless Patterns collection along with other Web Functions patterns. Read the Lambda Web Functions documentation to go deeper and the Lambda roadmap.
For more serverless learning resources, visit Serverless Land.
Some numbers are hard to picture until you sit with them for a moment. Last week we published the Prime Day 2026 metrics, and the one that stuck with me is 2.3 quadrillion: the daily requests Amazon ElastiCache peaked at during the event. Prime Day ran back in June, so this post always lands as a retrospective, and that gap is part of what makes it worth reading. By the time the numbers reach you, the only evidence that any of it happened is that nothing went wrong.
The rest of the week pulled in a different direction: smaller, cheaper, and more constrained. Claude Haiku 5.5 arrived on Amazon Bedrock at roughly 75 percent less than Haiku 4.5, Amazon Nova 2.5 Sonic made voice agents quicker on their feet, and Strands Box showed up to put real boundaries around what an agent is allowed to do. Now, let’s get into this week’s AWS news…
Headlines
All the numbers: Amazon Prime Day 2026 powered by AWS is the latest entry in a tradition that goes back to 2016, and the scale is still difficult to hold in your head. Over the four days of Prime Day, Amazon DynamoDB processed more than 59 trillion requests while peaking at 192 million requests per second, and kept single-digit millisecond responses throughout. AWS Lambda handled over 2.3 trillion invocations per day. Amazon EBS peaked above 24.8 trillion I/O operations, moving more than an exabyte of data daily. Amazon ECS launched an average of 158.3 million tasks per day on AWS Fargate, a 47.7 percent jump over last year, and AWS Graviton powered up to 49 percent of the Amazon EC2 compute that Amazon.com used.
The number I keep coming back to, though, isn’t a throughput record. The team ran more than 44,000 AWS Fault Injection Service experiments ahead of the event, more than six times what they ran in 2025. Those are deliberate failures injected on purpose, months in advance, so that the trillions of requests above turn into an ordinary shopping afternoon. If you’re preparing for your own peak moment, AWS Countdown Premium is built for exactly that kind of planning.
Last week’s launches
Here are some launches and updates from this past week that caught my attention:
Claude Haiku 5.5 is now available on AWS – You can now use the fastest model in the Claude 5.5 family on Amazon Bedrock and Claude Platform on AWS, at around 75 percent less than Claude Haiku 4.5 for most tasks. It’s the first Haiku with effort controls, so you can tune cost against intelligence per task instead of fixing one setting for a whole workload. It pairs naturally with Claude Opus 5.5: Opus plans and makes the judgment calls, and because Haiku is fast and cheap, you can run many Haiku subagents in parallel for routing, classification, and small code changes across many files.
Amazon Nova 2.5 Sonic for voice agents – You can now build real-time voice agents on a speech-to-speech Amazon Nova model with better reasoning, instruction following, and tool-calling accuracy, plus lower latency. That combination matters for multi-step work: a support agent can look up an order, check return eligibility, and start the return inside one conversation. It keeps expressive voices in seven languages, controllable turn-taking, and a 256K context window, and pairs with Strands Bidi Agents, now generally available, to get a production voice agent going in a few lines of code.
Amazon GuardDuty RDS Protection now detects data exfiltration and destruction – Amazon GuardDuty now looks past login anomalies to the queries themselves on Amazon Aurora PostgreSQL and Amazon RDS for PostgreSQL. RDS Protection for data activity builds behavioral baselines and uses ML-based anomaly detection plus threat intelligence to flag unusual data access, with no agents, extra infrastructure, or database configuration changes. This closes a real gap: once an attacker has valid credentials from phishing or a misconfiguration, their queries can look indistinguishable from your application’s.
AWS Lambda supports OAuth for self-managed Apache Kafka event sources – You can now authenticate Lambda Kafka consumers through your enterprise identity provider, such as Amazon Cognito or Okta. Event source mappings previously supported only SASL/PLAIN, SASL/SCRAM, and mTLS, which left teams in regulated industries unable to use Kafka ESM at all. Now you get the automatic scaling, batching, error handling, and event filtering of Kafka ESM with the same identity governance you apply everywhere else. It works with self-hosted clusters and managed offerings including Confluent Cloud, Aiven, and Redpanda.
For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.
Other AWS news
Here are some additional posts and resources that you might find interesting:
Introducing Strands Box: AI agent sandboxes powered by Dogwood – As more of us let agents run shell commands and call APIs without approving every step, isolation alone stops being enough. Strands Box is an open source sandbox (Apache 2.0, developer preview) that combines OS-level containment with fine-grained policies written in Dogwood, so permissions can depend on what the agent has already done. You can say “let the agent post to the incident channel, but no more than three times every 10 minutes” and have that enforced from outside the agent’s process. It also keeps real credentials out of the agent’s environment by attaching them at an egress gateway.
AWS Continuum sets a new standard in autonomous code security – Related to that theme, AWS Continuum for Penetration Testing now integrates into your CI/CD pipeline in public preview, turning penetration testing into a deploy-time event instead of something that happens off to the side. Developers get findings with severity, affected endpoints, and remediation guidance right in the pipeline output, and the pipeline re-tests to verify fixes.
Check your calendar and sign up for upcoming AWS events:
AWS re:Invent – re:Invent returns to Las Vegas from November 30 to December 4, and reserved seating is now open. The session catalog is live, so register and claim your spots in chalk talks, workshops, and builders’ sessions before they fill up.
AWS Community Days – Community-led conferences planned and delivered by community leaders, and this is a busy stretch. Upcoming stops include San Francisco (October 13), Miami (October 14), Brisbane (October 16), Cape Town (October 16), Malta (October 16), and Mumbai (October 17). Here in Brazil, the community calendar has more editions coming before the end of the year.
Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development. Browse here for upcoming AWS-led in-person and virtual events and developer-focused events.
That’s all for this week. Check back next Monday for another Weekly Roundup!
– Daniel Abib
This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!
Bad data rarely announces itself. It slips into an Amazon EMR pipeline quietly. A null where there should be a value. A timestamp in the wrong format. A referential key that no longer exists. It travels downstream until it surfaces as a wrong number in a dashboard, a failed downstream job, or a business decision made on data nobody verified.
For teams running large-scale data processing on Amazon EMR, choosing a data quality strategy has meant picking between two trade-offs. You can build your own quality checks in Apache Spark using an open source library like Deequ. With this approach, you can customize checks to your exact pipeline, but it adds custom code your team must maintain, with no centralized ruleset management and no consistent quality catalog across pipelines. Or you can route your data through AWS Glue to access its managed data quality capabilities. This approach minimizes the code you need to maintain but turns data quality validation into a separate step and adds another engine to your pipeline.
Today, there is a third option.
Amazon EMR Data Quality built on AWS Glue is now available natively on Amazon EMR, bundled in AWS runtime for Apache Spark (emr-spark-8.1.0) and later versions. You can write data quality rules using the same Data Quality Definition Language (DQDL) used in AWS Glue. Run them directly inside your Amazon EMR Spark jobs, across each of the three Amazon EMR deployment modes: Amazon EMR on EC2, Amazon EMR Serverless, and Amazon EMR on EKS.
This post walks through two patterns for using AWS Glue Data Quality, a capability of AWS Glue, on Amazon EMR. The first shows a lightweight ad hoc validation workflow, useful for exploratory processing and pipeline-local checks. The second builds on the Apache Iceberg Write-Audit-Publish (WAP) pattern. An extract, transform, and load (ETL) job writes data to an Iceberg branch, retrieves a managed ruleset from the AWS Glue Data Catalog, and validates the branch. Only if the data passes your quality bar does it merge to the main table. By the end of this post, you will have working examples of both patterns ready to run on any mode of Amazon EMR.
What is Amazon EMR Data Quality?
With Amazon EMR Data Quality, you can define and run data quality rules against your datasets. At its core is the Data Quality Definition Language (DQDL), a declarative rule syntax. With DQDL, you can express constraints like completeness, uniqueness, value ranges, referential integrity, and statistical distributions in plain, readable statements.
DQDL also includes machine learning (ML)-based anomaly detection. Rather than setting explicit thresholds, DetectAnomalies rules learn the statistical baseline of your data across runs and flag deviations automatically. This is useful for metrics that shift over time, like daily record counts or revenue totals, where a fixed range rule would require constant maintenance.
You can define rules inline within a job or store them as managed rulesets in the AWS Glue Data Catalog, a centralized metadata repository for table definitions and data quality rulesets. After the rules are stored, you can version these rulesets, share them across teams, and reuse them across multiple pipelines. The evaluator returns per-rule pass or fail results and an overall quality score. Your job can inspect the score to take action: fail the pipeline, write results to Amazon Simple Storage Service (Amazon S3), trigger an alert, or conditionally merge data.
You can now run this rule engine directly inside your Spark jobs on Amazon EMR. The same DQDL rulesets you author for AWS Glue work without modification.
For a full reference on DQDL syntax and rule types, see the AWS Glue Data Quality documentation.
Prerequisites and setup
Amazon EMR is a managed service for running Apache Spark and other open source big data frameworks on AWS. It offers three deployment modes: Amazon EMR on EC2, Amazon EMR Serverless, and Amazon EMR on EKS.
Before running the examples in this post, make sure you have the following in place.
Amazon EMR release: Amazon EMR Data Quality is bundled in AWS runtime for Apache Spark (emr-spark-8.1.0) and later versions across Amazon EMR on EC2, Amazon EMR on EKS, and Amazon EMR Serverless. No bootstrap action or additional installation is required. The library is available as part of the release.
AWS Identity and Access Management (IAM) permissions: The execution role for your Amazon EMR job needs the following permissions:
glue:AccessDataQualityRuntimeConfiguration to publish data quality results to the AWS Glue Data Catalog.
glue:CreateDataQualityRuleset to create managed rulesets in the AWS Glue Data Catalog.
glue:GetDataQualityRuleset to retrieve managed rulesets from the AWS Glue Data Catalog.
glue:GetDataQualityResult to read prior quality results.
glue:PublishDataQuality to submit data quality results to the AWS Glue Data Catalog.
glue:GetDatabase and glue:GetTable for catalog access.
Standard Amazon S3 read/write permissions for your data and output locations.
Pattern 1: Ad hoc data quality validation
This pattern defines data quality rules directly inside your Amazon EMR Spark job, with no externally managed ruleset to maintain.
The use case
Your team ingests a raw CSV file from a third-party vendor and needs to validate it before loading it into your data lake. The rules are straightforward: check that the record ID is never null, that revenue values are non-negative, and that country codes conform to an allowed list. This is a one-off check that lives entirely within the job. There is no centralized ruleset to manage, and the goal is to validate data quality before the load.
This pattern works well for:
Exploratory or one time processing pipelines.
Early-stage pipelines where rules are still evolving.
Lightweight validation that does not require centralized governance.
How it works
You define your DQDL rules inline as a string, pass your DataFrame and the rules to EvaluateDataQuality, and inspect the results to decide how the job should proceed.
To validate data quality inline using PySpark
To implement this pattern using PySpark, see the following code sample, which can be run on all three Amazon EMR deployment modes:
import os
from pyspark.sql import SparkSession
from awsdataquality.transforms import EvaluateDataQuality

spark = SparkSession.builder \
    .appName("dq-ruleset-catalog") \
    .enableHiveSupport() \
    .getOrCreate()

# Read new incoming data
input_df = spark.read.parquet("s3://amzn-s3-demo-sales-data/sales_data/incoming_data/")

# Contains our DQDL rules and analyzers. Analyzers submit statistics to the AWS Glue service for inspection. This can help create new rules.
ruleset = """
Rules = [
    RowCount > 0,
    IsPrimaryKey "order_id",
    Completeness "customer_email" >= 0.95,
    ColumnValues "order_status" in ["PENDING","SHIPPED","DELIVERED","RETURNED"],
    ColumnValues "net_amount" between 0.0 and 25000.0
]
Analyzers = [
    AllStatistics "net_amount",
    DistinctValuesCount "country",
    RowCount
]
"""

# Publishing options for the results of the data quality evaluation
publishing_opts = {
    "dataQualityEvaluationContext": "blog-post-dq-evaluation-context",
    "enableDataQualityResultsPublishing": "true"
}

# AWS Glue Data Quality uses the additional_options parameter to configure advanced evaluation behaviors, output formats, anomaly detection and performance tuning for data quality checks.
additional_opts = {"compositeRuleEvaluation.method": "ROW"}

# This set tells the Data Quality Evaluator if there are other data sources that
# we need to pull in for checks such as cross table reference checking.
additional_sources = {}

# Evaluate the ruleset against the data frame created by reading the parquet files and save
# the results in dq_results as a DataFrame.
dq_results = EvaluateDataQuality.apply(input_df, ruleset, publishing_opts, additional_opts,
    additional_sources)

print(f"{dq_results.count()} rule result row(s)")  # forces evaluation

# Iterate through the DQ results for any failed rules and if there are any failed
# rules, throw an exception to stop the job.
failures = []
for row in dq_results.collect():
    if row["Outcome"] == "Failed":
        failures.append(f"Rule: {row['Rule']} | Reason: {row['FailureReason']}")

if failures:
    failure_summary = "\n".join(failures)
    raise RuntimeError(f"Data quality checks failed:\n{failure_summary}")

# Write out data into the Iceberg table sales_data table
input_df.writeTo("company_sales.sales_data").append()
print(f"all rules passed; appending {input_df.count()} row(s) to company_sales.sales_data")
The preceding script passes the incoming DataFrame, an inline ruleset, and publishing options to EvaluateDataQuality, which runs the ruleset and returns a results DataFrame. The results DataFrame lists each rule with a Passed or Failed outcome and, for failed rules, the reason. The publishing options control if and where the results get published. The script raises an error and stops if any rule fails. If every rule passes, it appends the incoming data to the company_sales.sales_data table.
What the data quality results look like
The EvaluateDataQuality.apply() function returns the results as a DataFrame containing each rule, whether it passed or failed, and the evaluated rule. Your job can read this DataFrame and branch its logic accordingly: writing clean records to Amazon S3, routing failed records to a quarantine path, or halting the pipeline entirely. Following is sample output of the code earlier:
Rule
Outcome
FailureReason
EvaluatedMetrics
RowCount > 0
Passed
NULL
{RowCount -> 50000.0}
IsPrimaryKey “order_id”
Passed
NULL
{Uniqueness -> 1.0, Completeness -> 1.0}
Completeness “customer_email” >= 0.95
Passed
NULL
{Completeness -> 0.97924}
ColumnValues “order_status” in […]
Failed
Value: 0.99598 does not meet …
{ColumnValues.Compliance -> 0.99598}
ColumnValues “net_amount” between 0.0 and 25000.0
Failed
Value: -2228.87 does not meet …
{Minimum -> -2228.87, Maximum -> 3394.51}
RuntimeError: Data quality checks failed:
Rule: ColumnValues "order_status" in ["PENDING","SHIPPED","DELIVERED","RETURNED"] | Reason: Value: 0.99598 ...
Rule: ColumnValues "net_amount" between 0.0 and 25000.0 | Reason: Value: -2228.87 ...
Pattern 2: Iceberg Write-Audit-Publish with managed rulesets
This pattern gates data promotion on a centrally managed ruleset, merging new data into your main table only after it passes your quality checks.
The use case
Your team runs a nightly ETL job that transforms raw transactional data and writes it to an Apache Iceberg table. Apache Iceberg is an open table format for large analytic datasets that supports schema evolution, time travel, and branching on Amazon S3. Rather than writing directly to the production table and discovering quality issues after the fact, you want a safety gate. Write to a staging branch, validate it against your organization’s data quality standards, and only promote the data to the main table if it passes.
When combining AWS Glue Data Quality with WAP, you define your quality rules once in the AWS Glue Data Catalog and have your data governance team own them. You enforce them automatically at promotion time, without touching the pipeline code. Combined with managed rulesets in the AWS Glue Data Catalog, you get quality enforcement that is consistent and auditable. The data quality rules are also decoupled from the job code and changing them does not require touching the pipeline.
This pattern works well for:
Production ETL pipelines where bad data reaching the main table has downstream consequences.
Organizations with centralized data governance teams that own and version quality standards.
Apache Iceberg-based lakehouses where the WAP pattern is already in use.
How it works
The flow has four steps:
Retrieve the ruleset – Call the AWS Glue Data Catalog to fetch the managed ruleset for this table. The ruleset is owned by your governance team and versioned in the catalog.
Write to a branch – Before writing the ETL output, create an Apache Iceberg branch on the target table. Write all transformed records to this branch rather than to main.
Evaluate – Run EvaluateDataQuality against the branch data using the retrieved ruleset.
Merge or discard – If the quality score meets your threshold, merge the branch into main. If not, discard the branch and trigger your alerting workflow.
Creating a managed ruleset: To create a ruleset in the AWS Glue Data Catalog that targets the same database and table, you can create one using the AWS Command Line Interface (AWS CLI). For example:
The --target-table values must match the ICEBERG_DATABASE and ICEBERG_TABLE environment variables used in the Pattern 2 job. The job discovers the ruleset at runtime using list_data_quality_rulesets filtered by that target table.
To validate data quality inline using PySpark
To implement this pattern, see the following code sample which can be run on all three Amazon EMR deployment modes:
import os
import boto3
from pyspark.sql import SparkSession
from awsdataquality.transforms import EvaluateDataQuality

spark = (SparkSession.builder.appName("blog-wap-dq")
    .config("spark.sql.catalog.iceberg", "org.apache.iceberg.spark.SparkCatalog")
    .config("spark.sql.catalog.iceberg.warehouse", "s3://amzn-s3-demo-bucket/warehouse/")
    .config("spark.sql.catalog.iceberg.catalog-impl", "org.apache.iceberg.aws.glue.GlueCatalog")
    .enableHiveSupport().getOrCreate())

database = os.environ["ICEBERG_DATABASE"]
table = os.environ["ICEBERG_TABLE"]
input_path = os.environ["WAP_INPUT_PATH"]
threshold = float(os.environ.get("WAP_SCORE_THRESHOLD", "1.0"))
region = os.environ.get("AWS_REGION", "us-east-1")
ruleset_name = os.environ.get("GLUE_DQ_RULESET_NAME")

# Branch name carries the Spark application id so concurrent nightly runs, and reruns
# of a failed one, never collide on the same branch.
branch = os.environ.get("WAP_BRANCH") or f"audit_{spark.sparkContext.applicationId}"
branch = branch.replace("-", "_")
fqtn = f"iceberg.`{database}`.`{table}`"
branch_fqtn = f"iceberg.`{database}`.`{table}`.branch_{branch}"

glue = boto3.client("glue", region_name=region)

# ---------------------------------------------------------- 1. DQ RULESET
# We will then get the data quality rules.
ruleset = glue.get_data_quality_ruleset(Name=ruleset_name)["Ruleset"]
print(f"auditing against catalog ruleset '{ruleset_name}':\n{ruleset}")

# ---------------------------------------------------------- 2. WRITE
main_before = spark.table(fqtn).count()
print(f"main has {main_before} row(s) before this batch")

# CREATE BRANCH (not CREATE OR REPLACE): if the branch somehow already exists, that is
# a concurrent or half-finished run and silently replacing it would discard its state.
spark.sql(f"ALTER TABLE {fqtn} CREATE BRANCH {branch}")
print(f"created branch {branch}")

# Write out our batch to our new branch
batch = spark.read.parquet(input_path)
batch.writeTo(branch_fqtn).append()
print(f"wrote {batch.count()} row(s) to branch {branch}")

# Reread the branch and create a data frame to perform our data quality checks.
branch_df = spark.read.option("branch", branch).table(f"iceberg.`{database}`.`{table}`")

# ---------------------------------------------------------- 3. AUDIT
# Will now evaluate the ruleset against the branch
publishing_opts = {
    "dataQualityEvaluationContext": ruleset_name,
    "publishToDataCatalogTarget": {
        "DatabaseName": database,
        "TableName": table
    },
    "enableDataQualityResultsPublishing": "true"
}

# See the AWS Glue Data Quality additional_options reference for advanced configuration:
# https://docs.aws.amazon.com/glue/latest/dg/data-quality-additional-options.html
additional_opts = {}
additional_sources = {}

# Run EvaluateDataQuality.
dq_results = EvaluateDataQuality.apply(branch_df, ruleset, publishing_opts,
    additional_opts, additional_sources)

# ---------------------------------------------------------- 4. PUBLISH or discard
# Iterate through the DQ results for any failed rules and if there are any failed
# rules, throw an exception to stop the job.
failures = []
for row in dq_results.collect():
    if row["Outcome"] == "Failed":
        failures.append(f"Rule: {row['Rule']} | Reason: {row['FailureReason']}")

# If there are any failures of any rule, we will drop the branch, and throw an error
if failures:
    # Drop first, then raise: an exception alone would leave the rejected branch (and
    # its data files) behind on the table for every failed night.
    spark.sql(f"ALTER TABLE {fqtn} DROP BRANCH {branch}")
    main_after = spark.table(fqtn).count()
    print(f"REJECTED: branch {branch} dropped; main unchanged at {main_after} row(s)")
    failure_summary = "\n".join(r for r in failures)
    raise RuntimeError(f"Data quality checks failed:\n{failure_summary}")

# fast_forward moves main's pointer to the branch's snapshot. It requires main to
# be an ancestor of the branch, which holds here because the branch was cut from
# main and only appended to --- no rewrite of the promoted data, no second copy.
spark.sql(f"CALL iceberg.system.fast_forward("
    f"table => '{database}.{table}', branch => 'main', to => '{branch}')")
spark.sql(f"ALTER TABLE {fqtn} DROP BRANCH {branch}")
main_after = spark.table(fqtn).count()
print(f"PUBLISHED: main fast-forwarded to {branch} "
    f"({main_before} -> {main_after} row(s)); branch dropped")

spark.stop()
This code demonstrates a sample WAP approach using Apache Iceberg. We start by retrieving the ruleset from the AWS Glue service that will run against the table. We then create a branch within the Apache Iceberg table and apply new data against it. We then run our data quality checks using EvaluateDataQuality with the ruleset that we earlier obtained. If any of the data quality rules fail, a branch that holds the new version of the table gets dropped. Otherwise, it will be committed as the new main branch and made available for all consumers.
In this example, you will notice that the publishing_opts (publishing options) look different. For the dataQualityEvaluationContext, we set the ruleset name. We also fill in the publishToDataCatalogTarget with the database and table name within the AWS Glue Data Catalog. This tags the data quality run and its results to that table for easier lookups if you want to view the history of data quality runs on the table.
Clean up
To avoid ongoing charges, remove the resources that you no longer need:
Shut down Amazon EMR on EC2 clusters, Amazon EMR Serverless applications, or Amazon EMR on EKS.
Delete the tables that you created. The table mentioned in this blog post is company_sales.sales_data.
Delete the data quality ruleset created in Pattern 2.
Delete any Amazon S3 data that was generated for the purposes of this blog post.
Conclusion
Data quality is a concern for most production data pipelines. Until now, teams running on Amazon EMR had to build that quality layer themselves or bring in AWS Glue as a separate processing engine to get managed quality capabilities.
With AWS Glue Data Quality now bundled in AWS runtime for Apache Spark (emr-spark-8.1.0) and later versions, that gap is closed. You write your DQDL rules once and store them in the AWS Glue Data Catalog. From there, run them across each of the three Amazon EMR deployment modes.
The patterns in this post represent two points on that spectrum: a lightweight inline check for ad hoc workloads, and a full WAP workflow for production pipelines that need atomic, auditable data promotion.
Customers use AWS Lambda to build applications that connect to stateful, latency-sensitive backends such as Amazon ElastiCache, Amazon Relational Database Service (Amazon RDS), and other services that expose per-Availability Zone (AZ) endpoints. For high availability, Lambda automatically provisions your execution environments across multiple Availability Zones in a Region. That resilience is transparent to your code. It also means that, until now, a function had no way of knowing which Availability Zone it was running in. When a function in one AZ connects to a resource in another AZ, the request crosses the AZ boundary, adding network latency and, in some cases, cross-AZ data transfer costs.
Lambda now exposes Availability Zone metadata through a metadata endpoint in the execution environment. Your function can now discover its AZ ID (for example, use1-az1) with an HTTP request. You can use that information to prefer same-AZ endpoints for downstream services, reduce cross-AZ latency, and implement AZ-aware resilience patterns such as AZ-specific fault injection testing. The feature is available at no additional cost in all commercial AWS Regions where Lambda is available. It works across all runtimes, including custom runtimes and container images, and is compatible with SnapStart, provisioned concurrency, and functions in a virtual private cloud (VPC). For more information about these compatibility details, see Using the Lambda metadata endpoint.
In this post, you will learn how the Lambda metadata endpoint works, how to retrieve the AZ ID using Powertools for AWS Lambda or by calling the endpoint directly, and how to apply the AZ ID to route to same-AZ resources for lower latency.
Why Availability Zone awareness matters
Consider a latency-sensitive read path: an API-backed Lambda function that reads from an ElastiCache cluster with a node in each of three Availability Zones. Lambda places your execution environments across those same AZs for resilience, but the placement is independent of where each cache node lives. Roughly two out of three invocations end up talking to a cache node in a different AZ than the one the function is running in.
A same-AZ round trip typically completes in single-digit milliseconds. A cross-AZ round trip adds latency on top of that, and on a hot read path executed thousands of times per second, those milliseconds compound into higher p99 latency and additional cross-AZ data transfer charges. Before this feature, avoiding cross-AZ traffic from Lambda required custom workarounds. These included embedding AZ hints in environment variables per function version, or inferring locality from IP ranges, none of which were reliable.
The same pattern appears across many of the VPC-based, AZ-scoped services your functions connect to. With Amazon RDS and Amazon Aurora, the writer instance lives in a single AZ, and each read replica lives in an AZ of its own. A read-heavy function that spreads its queries across replicas will, more often than not, reach a replica in a different AZ. Once your function knows its own AZ ID, you can direct reads to the replica that shares it. This keeps the hot query path in-AZ while still failing over to another replica when no same-AZ one is available. For more information, see Configuring Aurora read replica load balancing.
Amazon MemoryDB extends the same idea to a durable primary/replica topology: writes go to the shard’s primary in one AZ, while reads can be served from replicas spread across the others. Consider a high-volume, read-mostly path that tolerates eventual consistency, such as looking up reference data or serving cached lookups. Steering reads to the replica in the function’s AZ keeps the hottest part of the workload in-AZ, while writes continue to route to the primary wherever it lives. Because replicas lag the primary by a small, asynchronous delay, send any read that must reflect its own write directly to the primary rather than to a same-AZ replica.
Container platforms exhibit the same behavior when Lambda calls into them. If your function invokes a service running on Amazon Elastic Kubernetes Service (Amazon EKS) or Amazon Elastic Container Service (Amazon ECS), the pods or tasks behind that service are distributed across AZs, and by default a request can land on any of them. You can combine the function’s AZ ID with topology-aware routing to keep east-west traffic within the AZ. Examples include Kubernetes Topology Aware Routing or an internal load balancer with cross-zone balancing tuned. The same reasoning applies to a function calling a private service fronted by an internal Application Load Balancer or discovered through AWS Cloud Map: knowing the caller’s AZ turns “any healthy target” into “the nearest healthy target.”
The metadata endpoint removes that guesswork. Your function asks the execution environment where it is running, gets back a stable AZ ID, and routes accordingly.
Figure 1: AZ-aware reads and centralized writes with the AWS Lambda metadata endpoint
How the metadata endpoint works
The metadata endpoint is a loopback HTTP API available inside the Lambda execution environment, accessible to both runtimes and extensions. Lambda automatically sets two environment variables in every execution environment:
AWS_LAMBDA_METADATA_API – The metadata server address in the format {ipv4_address}:{port} (for example, 169.254.100.1:9001). For more information about how this address and port are assigned, see Using the Lambda metadata endpoint.
AWS_LAMBDA_METADATA_TOKEN – A unique authentication token for the current execution environment, generated automatically at initialization. You include it in every metadata API request.
You retrieve metadata with an authenticated GET request:
GET http://${AWS_LAMBDA_METADATA_API}/2026-01-15/metadata/execution-environment
The response is a small JSON document:
{
  "AvailabilityZoneID": "use1-az1"
}
The Authorization header must contain a Bearer token (Authorization: Bearer <token>). This token-based authentication provides defense in depth against Server-Side Request Forgery (SSRF) vulnerabilities. Each execution environment receives its own randomly generated token, so a leaked or guessed URL alone is not enough to read metadata.
The response is immutable within an execution environment and returns a Cache-Control: private, max-age=43200, immutable header. We recommend that you cache the response and respect the TTL rather than calling the endpoint on every invocation. For SnapStart functions, the TTL is reduced during initialization so that clients refresh the metadata after restore, since a restored execution environment might come up in a different AZ. For more information, see Lambda SnapStart metadata behavior.
Retrieving the AZ ID with Powertools for AWS Lambda
The most direct way to consume the endpoint is with the Powertools for AWS Lambda metadata utility, available for Python, TypeScript, Java, and .NET. The utility caches the response after the first call and handles SnapStart cache invalidation automatically, so you don’t need to manage tokens, HTTP requests, or TTLs yourself. The following examples show how to use Powertools in each language.
using Amazon.Lambda.Core;
using AWS.Lambda.Powertools.Metadata;

public class Function
{
    public string Handler(object input, ILambdaContext context)
    {
        var azId = LambdaMetadata.AvailabilityZoneId;
        return $"Running in AZ: {azId}";
    }
}
Calling the metadata endpoint directly
If you use a custom runtime, a container image, or prefer not to add a dependency, you can call the endpoint directly using the environment variables Lambda sets for you. The following example uses curl and jq to read the AZ ID:
# Variables are automatically set by Lambda
METADATA_ENDPOINT="http://${AWS_LAMBDA_METADATA_API}/2026-01-15/metadata/execution-environment"

# Make the request
RESPONSE=$(curl -s -w "\n%{http_code}" -H "Authorization: Bearer ${AWS_LAMBDA_METADATA_TOKEN}" "$METADATA_ENDPOINT")

HTTP_CODE=$(echo "$RESPONSE" | tail -1)

if [ "$HTTP_CODE" != "200" ]; then
  echo "Metadata request failed with status $HTTP_CODE" >&2
  exit 1
fi

# Parse the AZ ID
AZ_ID=$(echo "$RESPONSE" | sed '$d' | jq -r '.AvailabilityZoneID')

echo "Function is running in AZ ID: $AZ_ID"
Notice the configuration:
AWS_LAMBDA_METADATA_API: Lambda sets this to the metadata server address, so you never hardcode the host or port.
Authorization: Bearer ${AWS_LAMBDA_METADATA_TOKEN}: The token is required on every request. A missing or invalid token returns 401 Unauthorized.
GETonly: The endpoint accepts GET requests. Any other method returns 405 Method Not Allowed.
When you call the endpoint directly, retrieve the AZ ID once during initialization (outside the handler) and cache it for the life of the execution environment, rather than calling on every invocation. If your function uses SnapStart, refresh the value after restore, because the restored environment might run in a different AZ.
Understanding Availability Zone IDs
The endpoint returns an AZ ID (for example, use1-az1), not an AZ name (for example, us-east-1a). Before you use it, it helps to read the ID itself. An AZ ID follows the pattern <region-code>-az<number>:
use1 is the shortened Region code, in this case US East 1 (us-east-1). Other Regions follow the same convention, such as usw2 for US West (Oregon) and euw1 for Europe (Ireland).
az1 identifies the individual Availability Zone within that Region. So use1-az1 reads as “Availability Zone az1 in us-east-1.”
This distinction matters. AZ IDs always refer to the same physical location across all AWS accounts, while AZ names might map to different physical infrastructure in each account in certain Regions. In other words, the us-east-1a name in your account and the us-east-1a name in another account can point to two different physical Availability Zones, but use1-az1 is the same physical zone in every account. There is no fixed mapping between a name like us-east-1a and an ID like use1-az1. AWS assigns names independently per account to balance resources across zones. That’s exactly why the endpoint returns the ID: comparing AZ IDs gives you a consistent, account-independent result about whether your function and a downstream resource share a physical Availability Zone. For more information, see AZ IDs for cross-account consistency.
If you need the AZ name (for example, for logging or for an API that expects a name), convert the AZ ID using the Amazon Elastic Compute Cloud (Amazon EC2)DescribeAvailabilityZones API. To call it, add the ec2:DescribeAvailabilityZones permission to your function’s execution role:
Retrieving the AZ ID is only useful if you act on it. The following Python example shows the common pattern illustrated in Figure 1: look up the AZ ID once at initialization, select the connection endpoint that lives in the same AZ, and fall back gracefully when there is no same-AZ match.
from aws_lambda_powertools.utilities.metadata import LambdaMetadata, get_lambda_metadata

# Map each cache node to the AZ ID it lives in.
# Populate this from configuration (for example, environment variables or Parameter Store).
CACHE_NODES_BY_AZ = {
    "use1-az1": "cache-node-1.example.use1-az1.cache.amazonaws.com",
    "use1-az2": "cache-node-2.example.use1-az2.cache.amazonaws.com",
    "use1-az3": "cache-node-3.example.use1-az3.cache.amazonaws.com",
}

# Read the AZ ID once during initialization (cached across warm invocations).
AZ_ID = get_lambda_metadata().availability_zone_id

# Prefer the same-AZ node; fall back to any node if there isn't one.
CACHE_ENDPOINT = CACHE_NODES_BY_AZ.get(AZ_ID) or next(iter(CACHE_NODES_BY_AZ.values()))


def handler(event, context):
    # Use CACHE_ENDPOINT for your read path. When AZ_ID matches the node's AZ,
    # the request stays within the Availability Zone.
    return {"az_id": AZ_ID, "cache_endpoint": CACHE_ENDPOINT}
Notice the design choices:
Resolve at initialization: AZ_ID and CACHE_ENDPOINT are computed once per execution environment, not per invocation, so the metadata lookup and endpoint selection don’t add latency to the request path.
Always provide a fallback: If there is no node in your function’s AZ (for example, the service isn’t deployed in every AZ the function runs in), fall back to any available endpoint. Correctness must not depend on a same-AZ match being present.
Compare AZ IDs, not names: Because the endpoint returns AZ IDs, and services like ElastiCache and RDS expose the AZ of their nodes, you can compare the two directly for a reliable same-AZ decision.
Beyond latency-aware routing, the same AZ ID unlocks resilience testing. You can, for example, inject faults only in functions running in a specific AZ to validate that your application degrades gracefully during a simulated AZ impairment, without affecting traffic served from other AZs.
Best practices
Based on the endpoint’s behavior, keep these recommendations in mind:
Cache the metadata: The response is immutable for the life of an execution environment. Read it once at initialization and reuse it. If you call the endpoint directly, respect the Cache-Control TTL rather than requesting on every invocation.
Handle SnapStart correctly: A restored SnapStart environment might resume in a different AZ than the one it was snapshotted in. Refresh the AZ ID after restore. Powertools handles this invalidation for you automatically.
Ignore unknown fields: Additional fields might be added to the response in the future. Parse defensively and don’t fail if new fields appear.
Degrade gracefully: Treat same-AZ routing as an optimization, not a requirement. Always keep a working fallback path so your function stays correct when no same-AZ resource is available.
Keep the token server-side: The AWS_LAMBDA_METADATA_TOKEN is scoped to a single execution environment. Never log it or forward it outside the function.
Conclusion
In this post, you learned how the Lambda metadata endpoint helps your functions discover the Availability Zone they run in. With a single authenticated HTTP request, or one call through Powertools for AWS Lambda, your function can retrieve a stable AZ ID and use it to route to same-AZ resources, cutting cross-AZ latency and data transfer on hot paths, and to build AZ-aware resilience patterns like targeted fault injection. The feature works across all runtimes, integrates with SnapStart, provisioned concurrency, and VPC-enabled functions, and is available at no additional cost in all commercial AWS Regions where Lambda is available.
The key takeaway: if your Lambda function reads from or writes to AZ-scoped resources such as ElastiCache or RDS on a latency-sensitive path, resolve the AZ ID at initialization, prefer the same-AZ endpoint, and always keep a fallback. You get lower, more predictable latency with no change to how Lambda manages high availability for you.
AWS Lambda recently launched SnapStart for container image functions, reducing startup times from several seconds to as low as sub-second. Customers deploy Lambda functions with container images to align with their organization’s container-based deployment standards, or to package larger dependencies up to 10 GB. However, larger container images can experience startup times of several seconds as Lambda downloads image layers and initializes the runtime and application code. SnapStart addresses this by taking a snapshot of the initialized execution environment during function deployment, caching it, and resuming from it on invocation, instead of initializing from scratch.
In November 2022, Lambda launched SnapStart for Java, reducing startup latency by up to 10x. In November 2024, SnapStart expanded to Python and .NET managed runtimes, reducing cold start latency to as low as sub-second. These launches helped developers achieve faster startup time, but only for .zip file archives. By extending SnapStart support for container image functions, customers can improve startup times for latency-sensitive workloads such as ML inference and interactive APIs.
This post covers how SnapStart for container images works, how to enable it, and best practices and considerations for your workloads.
How SnapStart for container images works
When you deploy a Lambda function, you choose one of two deployment models: a .zip file archive or a container image. With managed runtimes we already support SnapStart for Python, .NET, and Java functions, and now we have extended this capability to container images. When you invoke the deployed function for the first time, or when a burst of traffic arrives, Lambda checks if there is an available execution environment. If none are available, Lambda creates a new one.
For container image functions, this means downloading and extracting image layers, bootstrapping the runtime, and running your initialization code. This process can take several seconds, which users experience as a cold start.
When you enable SnapStart and publish a function version, Lambda proactively creates an execution environment, initializes your function, and then takes a Firecracker microVM snapshot of the full memory and disk state. This snapshot is encrypted and cached for low latency access and remains cached until you delete the corresponding function version.
On invocation, Lambda resumes from the cached snapshot rather than initializing from scratch. With SnapStart, initialization happens once at deployment time rather than on every invocation, replacing the initialization phase with a faster restore phase that speeds up startup time to as low as sub-second.
Figure 1: SnapStart for container images lifecycle, from image push to snapshot restore at invocation
Supported base images
For managed runtimes, you provide your code, and Lambda handles the runtime environment. For container image functions, you package your own runtime environment using Lambda-vended base images or your own custom base images. SnapStart for container images supports the following Lambda base images at launch. To learn about supported base images per runtime, see the Lambda SnapStart developer guide.
Runtime
Base Image
Architecture
Java 11 and later
public.ecr.aws/lambda/java:11, :17, :21, :25
x86_64, arm64
Python 3.12 and later
public.ecr.aws/lambda/python:3.12, :3.13, :3.14
x86_64, arm64
.NET 8 and later
public.ecr.aws/lambda/dotnet:8, :9, :10
x86_64, arm64
Regardless of which base image you use, there is an important consideration to understand before enabling SnapStart. When Lambda restores a function from a snapshot, any state captured during initialization is shared across all execution environments restored from that snapshot. This includes random number generators, unique IDs, cached credentials, and database connections. Your function needs to restore a unique state after each resume to avoid reusing the same random seed or an expired database connection across invocations. For more details on these considerations, see SnapStart uniqueness documentation.
To help you restore uniqueness for your application, Lambda provides runtime hooks for managed runtimes that let you run your own code at specific points in the snapshot-and-restore cycle. With SnapStart for container images, we are extending these same hooks to container image functions.
If your function uses one of the preceding Lambda-managed base images, Lambda offers runtime hooks for you to run your code (for example, to restore database connections). Lambda supports these runtime hooks for Java through CRaC, for Python through snapshot_restore_py, and for .NET through SnapshotRestore. To register your own before-snapshot and after-restore hooks for these runtimes, see SnapStart runtime hooks documentation.
If your function uses a base image without native SnapStart support (for example, a Node.js or Ruby base image), a custom Runtime Interface Client, or a custom runtime built on provided.al2023, review the documentation on implementing SnapStart hooks for container image functions and choose one of the following options.
Option 1: Implement SnapStart runtime hooks. If you need to run custom logic when your function is snapshotted or restored, implement the /restore/next API in your container image as described in SnapStart runtime hooks documentation.
Option 2: Opt in without hooks. If you do not need before-snapshot or after-restore hooks, add the following label to your Dockerfile (LABEL com.amazonaws.lambda.feature.snapstart=”Allow”)
For a reference implementation of SnapStart runtime hooks integration in a custom runtime, refer to the Lambda Rust Runtime repository, including its examples for both event-driven and HTTP functions to see how SnapStart and runtime hooks are implemented.
To use SnapStart with a container image function, your function must be deployed with PackageType Image, and the image must be pushed to an Amazon Elastic Container Registry (Amazon ECR) repository in the same AWS Region as your function. The examples in this section use a supported Lambda base image and us-east-1 as the AWS Region. Either set your default region or add –region to each command.
Activating SnapStart on an existing function
If you already have a container image function using a supported base image, activate SnapStart by updating the function configuration and publishing a version:
Start with a Dockerfile using a supported base image. Here is an example for Python:
FROM public.ecr.aws/lambda/python:3.12
COPY requirements.txt ${LAMBDA_TASK_ROOT}
RUN pip install -r requirements.txt
COPY lambda_function.py ${LAMBDA_TASK_ROOT}
CMD ["lambda_function.handler"]
Build, push to Amazon ECR, and create the function with SnapStart in a single flow:
# Build the container image locally. --platform pins the CPU architecture
# (must match --architectures on create-function). --provenance=false is
# required because BuildKit otherwise wraps the image in an OCI image index
# (manifest list) to attach a provenance attestation, and Lambda only accepts
# a single image manifest.
docker buildx build --platform linux/amd64 --provenance=false -t my-function-repo:latest .

aws ecr get-login-password | \
docker login --username AWS --password-stdin 111122223333.dkr.ecr.us-east-1.amazonaws.com
docker tag my-function-repo:latest 111122223333.dkr.ecr.us-east-1.amazonaws.com/my-function-repo:latest
docker push 111122223333.dkr.ecr.us-east-1.amazonaws.com/my-function-repo:latest

aws lambda create-function \
    --function-name my-function \
    --package-type Image \
    --code ImageUri=111122223333.dkr.ecr.us-east-1.amazonaws.com/my-function-repo:latest \
    --role arn:aws:iam::111122223333:role/lambda-execution-role \
    --architectures x86_64 \
    --snap-start ApplyOn=PublishedVersions

# Once the function is active, publish the version
aws lambda publish-version \
    --function-name my-function
Verifying SnapStart is active
After publishing, check the function version configuration:
Note that SnapStart applies only to published versions, not $LATEST. You must invoke a specific version number to use SnapStart.
Best practices and considerations
As SnapStart resumes your function from a point-in-time snapshot, here are some best practices to consider for resources initialized at snapshot time that may become stale when your function resumes, such as network connections, credentials, and unique IDs.
Performance tuning: Preload dependencies and initialize resources in your init code rather than the handler. This moves heavy setup into the snapshot, where it’s captured once and reused across restores. For guidance on optimizing function startup latency, see the performance tuning section of the Lambda developer guide.
Network connections: Since snapshots can persist over an extended period, connections established during initialization may no longer be valid after restore. Network connections established through an AWS SDK resume automatically. For connections your code manages directly, such as database connections, use after-restore hooks to re-establish them as described in the networking best practices section of the Lambda developer guide.
Uniqueness: Avoid generating unique IDs, secrets, or random values during initialization, because these are shared across all execution environments restored from the same snapshot. Instead, generate them in the function handler or use after-restore hooks. Software that always gets random numbers from the operating system (for example, from /dev/random or /dev/urandom) does not need any updates to maintain randomness. Lambda always reseeds /dev/random and /dev/urandom when restoring a snapshot, so random numbers are not repeated even when multiple execution environments resume from the same snapshot. For more details on managing unique state across restores, see the handling uniqueness documentation for Lambda SnapStart.
Ephemeral data: Cached credentials, timestamps, or other time-sensitive data captured during initialization may be stale by the time your function resumes from a snapshot. Use after-restore hooks to verify freshness and refresh any expired state before processing requests.
Monitoring:Amazon CloudWatch logs include a RESTORE_REPORT line showing the time spent restoring the snapshot. The REPORT line includes Restore Duration, Billed Restore Duration, Duration, and Billed Duration. Note that InitDuration does not appear for SnapStart invocations because the function resumes from a snapshot rather than initializing. You can also use AWS X-Ray active tracing to capture real-time telemetry for extensions through the Telemetry API, and measure end-to-end latency with Amazon API Gateway and Lambda function URL metrics. To learn more about available monitoring options, visit the Lambda documentation on monitoring for SnapStart.
SnapStart for container images uses the same pricing dimensions as SnapStart for Python 3.12+ and .NET 8+. You pay for the cost of caching a snapshot per function version that you publish with SnapStart enabled, and the cost of restore each time a function is restored from a snapshot. To reduce your caching costs, delete unused function versions. Refer to the Lambda pricing page for more details.
Lambda SnapStart for container images is available in all commercial AWS Regions except Asia Pacific (New Zealand) and Asia Pacific (Taipei). For the latest list of supported Regions, see the Lambda SnapStart supported regions.
Cleanup
To avoid ongoing charges for the resources created in this walkthrough, delete them when you are done. Deleting a Lambda function version removes the associated cached snapshot and stops any related snapshot caching charges.
Delete the Lambda function. This removes all published versions and their cached snapshots:
If you created an IAM execution role only for this walkthrough, delete it as well. For details, see deleting an IAM role.
Conclusion
In this post, we described how Lambda SnapStart for container images reduces cold start latency by snapshotting the initialized execution environment and resuming from it on subsequent invocations. We covered how SnapStart works, how to get started based on your base image type, best practices and considerations, and pricing and availability. We look forward to hearing from you about the future capabilities you need for SnapStart, on our Lambda Roadmap GitHub page.
Analytics teams on AWS often store data in more than one open table format, and that data frequently lives in more than one AWS account. Two problems follow: querying across table formats without catalog-level complexity, and joining data across accounts without copying it. This is common in a data mesh, where domain teams own data in separate AWS accounts while analytics workloads run centrally. Multi-catalog support in Amazon EMR 8.1.0 addresses both problems.
Amazon EMR release 8.1.0 addresses both challenges with multi-catalog support. The RedirectingSessionCatalog (RSC) is an opt-in catalog that you set as the Spark default. It automatically detects each table’s format from AWS Glue metadata, routes queries to the correct format handler, and supports multiple AWS Glue Data Catalogs across AWS accounts. With multi-catalog support, you can query Iceberg, Hudi, Delta Lake, and Hive tables through a single unified catalog. You can also join tables across AWS accounts without copying data and discover remote catalogs dynamically at query time.
In this post, we show how to put these capabilities into practice using Amazon EMR Serverless.
The Spark single-catalog constraint
Many formats. The Spark default catalog (spark_catalog) accepts only one CatalogExtension at a time: SparkSessionCatalog for Iceberg, DeltaCatalog for Delta Lake, or HoodieCatalog for Hudi. You configure one, and queries against tables in other formats fail unless those tables are registered in a separate, format-specific catalog.
Many accounts. The Spark V1 metastore (ExternalCatalog) is a singleton bound to one AWS Glue Data Catalog in one account. The Spark V2 catalog API supports named catalogs, but only Iceberg uses it. Delta Lake, Hudi, and Hive tables still rely on V1. As a result, cross-account access for those formats required complex multi-step workarounds. These included AWS Lake Formation grants, AWS Resource Access Manager (AWS RAM) shares, resource links, and per-table permissions.
Amazon EMR 8.1.0 addresses both constraints with the RedirectingSessionCatalog, described in the following section.
The RedirectingSessionCatalog
The RedirectingSessionCatalog provides three opt-in, backward-compatible capabilities. Set RSC as the default catalog to run multi-format queries without format-specific prefixes. Declare a named RSC catalog to join across accounts without data copies. Turn on the AWS Glue Data Catalog resolver to discover and register remote catalogs at query time, with no upfront spark.sql.catalog.* configuration. The following sections cover each capability.
Multi-format support
In Amazon EMR 8.1.0, you set the default catalog to the RedirectingSessionCatalog (RSC). On table resolution, RSC calls the AWS Glue Data Catalog, reads the table’s format from its metadata, caches the result, and delegates to the matching format-specific catalog (Iceberg, Delta Lake, Hudi, or Hive).
Without this feature, you had to register a separate catalog for each format and prefix every table reference:
# One catalog per format, all pointing at the same Glue metastore
spark.sql.catalog.spark_catalog = org.apache.iceberg.spark.SparkSessionCatalog
spark.sql.catalog.delta_catalog = org.apache.spark.sql.delta.catalog.DeltaCatalog
spark.sql.catalog.hudi_catalog = org.apache.spark.sql.hudi.catalog.HoodieCatalog

# Queries must use format-specific catalog prefixes
SELECT * FROM spark_catalog.db.iceberg_table;
SELECT * FROM delta_catalog.db.delta_table;
SELECT * FROM hudi_catalog.db.hudi_table;
With multi-format support, this reduces to a single catalog property:
What you set:
# Replace the default catalog with RedirectingSessionCatalog.
# RSC auto-detects each table's format from Glue metadata.
spark.sql.catalog.spark_catalog = org.apache.spark.sql.connector.catalog.\
redirecting.RedirectingSessionCatalog
How you query:
-- No format prefixes needed. RSC resolves the format at query time.
SELECT * FROM db.iceberg_table;
SELECT * FROM db.delta_table;
SELECT * FROM db.hudi_table;

-- Cross-format joins work in a single statement.
SELECT i.id, d.val, h.val
FROM db.iceberg_table i
JOIN db.delta_table d ON i.id = d.id
JOIN db.hudi_table h ON i.id = h.id;
On table resolution, RSC:
Calls the AWS Glue Data Catalog to read table metadata.
Inspects the table’s Parameters map to determine the format (Iceberg, Delta Lake, Hudi, or Hive/Parquet).
Delegates the operation to the appropriate format-specific catalog implementation.
The following diagram shows how a single query flows through the RedirectingSessionCatalog to the correct format handler.
Figure 1: Multi-format routing. A single query enters the RedirectingSessionCatalog, which calls the AWS Glue Data Catalog to read each table’s format, then routes the table to the matching format-specific handler (Iceberg, Delta Lake, Hudi, or Hive) so results return through one catalog
As the diagram illustrates, the query enters through spark_catalog (the RSC). The RSC reads each table’s format from the AWS Glue Data Catalog and routes the operation to the matching engine: Iceberg, Delta Lake, Hudi, or Hive/Parquet. The four format handlers read the underlying data files from Amazon Simple Storage Service (Amazon S3). The caller issues one query with no format-specific catalog prefixes.
Multi-catalog: Cross-account access
When production data lives in a separate AWS account from your analytics compute, you can declare a named RSC catalog that points at that account’s AWS Glue Data Catalog. RSC resolves tables in the remote account the same way it resolves local tables, so a single query can join across accounts without copying data.
Previously, cross-account table resolution worked only for Iceberg (V2 catalog). Hive, Delta Lake, and Hudi tables in another account required manual Lake Formation and AWS RAM configuration rather than catalog-level resolution. With Amazon EMR 8.1.0, you declare a named RSC catalog for the remote account:
Configuration:
# Declare a named catalog pointing at the remote account's Glue catalog.
# "prod" is any name you choose for this catalog.
spark.sql.catalog.prod = org.apache.spark.sql.connector.catalog.\
redirecting.RedirectingSessionCatalog

# Tell it to use Glue as the metastore backend.
spark.sql.catalog.prod.metastore.type = glue

# Point it at the remote account's Glue catalog ID.
spark.sql.catalog.prod.metastore.hadoop.hive.metastore.glue.catalogid = 111122223333
Query:
-- Join local and remote tables directly. No data copy.
SELECT o.order_id, f.status
FROM spark_catalog.analytics.orders o -- local Iceberg table
JOIN prod.salesdb.fulfillment f -- remote Hudi table (account 111122223333)
ON o.order_id = f.order_id;
Each named RSC instance creates its own V1 metastore delegate and registers it with the global SessionCatalog, removing the singleton limitation.
The following diagram shows how a single query joins tables across two AWS accounts through named catalogs.
Figure 2: Cross-account access. A query in the local account references a named RSC catalog that points at a second account’s AWS Glue Data Catalog, so the local and remote tables join in one query without copying data between accounts
As the diagram illustrates, the analytics account uses spark_catalog (the RSC) for its local Glue Data Catalog, while a named catalog (prod) points at the production account’s Glue Data Catalog. The query joins a local table to a remote table in a single statement, shown by the JOIN between the two accounts. Each account keeps its own Glue Data Catalog, and no data is copied between them.
Auto-wiring
The preceding multi-catalog setup requires you to pre-declare each remote catalog in spark.sql.catalog.* properties. Auto-wiring in Amazon EMR 8.1.0 removes this requirement at two levels.
Before Amazon EMR 8.1.0, you declared the resolver, a handler per format, and each handler’s delegate class explicitly:
# Set the default catalog. EMR auto-registers Iceberg, Delta, Hudi handlers.
# No handler.* properties needed.
spark.sql.catalog.spark_catalog = org.apache.spark.sql.connector.catalog.\
redirecting.RedirectingSessionCatalog

# Enable catalog discovery. The resolver inspects the connection type and
# registers the catalog at query time, with no upfront spark.sql.catalog.* config.
spark.sql.catalogResolver = com.amazonaws.glue.catalog.\
redirecting.GlueCatalogResolver

# Optional. Falls back to the SDK default region chain. Set this to query Glue catalogs in a specific region.
spark.sql.catalogResolver.region = us-east-1
Query:
-- Reference a remote catalog by its account ID. No prior declaration exists.
-- EMR calls Glue GetCatalog, determines the type, registers it on the spot.
SELECT o.order_id, f.status
FROM spark_catalog.analytics.orders o
JOIN `111122223333`.sales.fulfillment f
ON o.order_id = f.order_id;
The AWS Glue Data Catalog resolver is opt-in. When enabled, Amazon EMR issues an AWS Glue GetCatalog API call each time a query references a catalog that hasn’t been registered. This isn’t enabled by default to avoid unintended API calls for catalog names that don’t exist.
At the handler level, setting the default catalog to RedirectingSessionCatalog is enough. Amazon EMR fills in the Iceberg, Delta, and Hudi handlers automatically, so you don’t need to write handler.* properties.
At the catalog level, when you enable the Glue catalog resolver, Amazon EMR discovers new catalogs on demand. The first time a query references an undeclared catalog, Amazon EMR calls the AWS Glue GetCatalog API, inspects the connection type, and registers the catalog at query time.
Dynamic discovery is functional in Amazon EMR 8.1.0 for three catalog types. For standard cross-account AWS Glue catalogs, the resolver registers a redirecting catalog and multi-format routing applies. For Amazon S3 Tables, a capability of Amazon S3, the resolver reads the federated AWS Glue metadata and routes through Iceberg for both reads and writes. It also supports Amazon Redshift Managed Storage.
The following diagram shows how the GlueCatalogResolver discovers and registers a catalog the first time a query references it.
Figure 3: Auto-wiring. When a query references an undeclared catalog, the Glue catalog resolver calls the AWS Glue GetCatalog API, inspects the connection type, and registers the catalog at query time, so no upfront catalog configuration is required
As the diagram illustrates, a query references a catalog that has not been declared, which raises a catalog-not-found condition. The GlueCatalogResolver intercepts it and calls the AWS Glue Data Catalog through the GetCatalog API. Based on the connection type, the resolver registers the appropriate catalog: a redirecting catalog for a cross-account AWS Glue Data Catalog, a push-down catalog for Redshift Managed Storage, or a Spark catalog for Amazon S3 Tables. Registration happens at query time, with no upfront configuration.
Quick start
Follow these steps to enable multi-catalog support on an existing Amazon EMR 8.1.0 application:
1. Set spark_catalog to the RedirectingSessionCatalog:
Step 1 is all you need for Iceberg-only multi-format queries. The notes call out additional configuration for Delta Lake, Hudi, or cross-account scenarios. Step 2 removes the need to pre-declare catalogs by resolving them at query time.
Try it yourself
The following walkthrough creates four tables (one per format), runs a cross-format join, and extends to a cross-account query. The accompanying sample scripts handle resource creation, job submission, and cleanup. The accompanying code is in the aws-emr-utilities repository.
Prerequisites
An AWS account with permissions for Amazon EMR Serverless, AWS Glue Data Catalog, and Amazon S3.
An Amazon EMR Serverless application running release emr-spark-8.1.0 (Spark). The multi-catalog features also work on Amazon EMR on EC2 and Amazon EMR on EKS.
An Amazon EMR Serverless job execution role scoped to the specific AWS Glue databases and S3 prefixes.
An S3 bucket for scripts and output (this post uses s3://amzn-s3-demo-bucket/multicatalog/).
(For cross-account) A producer account with Lake Formation grants, AWS Glue resource policy, Amazon S3 bucket policy, and AWS Key Management Service (AWS KMS) key policy configured.
Step-by-step implementation
Step 1: Clone the repository and configure
git clone https://github.com/aws-samples/aws-emr-utilities.git
cd aws-emr-utilities/examples/emr-multi-catalog
cp env.template .env
# Edit .env with your application ID, role ARN, bucket, and region
The repository contains two phases: single-account multi-format and cross-account. The .env file stores resource identifiers referenced by all scripts.
Step 2: Bootstrap the environment
./scripts/bootstrap.sh
This script creates the AWS Glue database, uploads PySpark scripts to S3, and verifies that your Amazon EMR Serverless application is in CREATED state. Note the application ID from the output if you have not set it in .env.
Step 3: Create tables across four formats
./scripts/run_demo.sh --phase setup
The setup phase submits a PySpark job that creates one table per format (Iceberg, Delta Lake, Hudi, Hive/Parquet) in a single AWS Glue database with a shared id/val schema. Each CREATE TABLE uses a different USING clause but all go through the same spark_catalog. RSC routes each to the correct engine.
The job configuration includes the RedirectingSessionCatalog, OTF session extensions for Delta and Hudi, and KryoSerializer for Hudi. If your workload is Iceberg-only, you can omit the extensions and serializer.
Step 4: Run the cross-format join
./scripts/run_demo.sh --phase query
This submits a query that references four tables by database.table only, with no format prefix. The query joins all four through a single catalog with no format-specific configuration:
SELECT i.id, i.val AS iceberg, d.val AS delta, h.val AS hudi, p.val AS hive
FROM salesdb.orders_iceberg i
JOIN salesdb.returns_delta d ON i.id = d.id
JOIN salesdb.shipments_hudi h ON i.id = h.id
JOIN salesdb.products_hive p ON i.id = p.id;
Each column came from a different table format, joined in one query with no format-specific catalog configuration.
Step 5: (Optional) Extend to cross-account
Cross-account access requires grants from the account that owns the data. Run one bootstrap in each account:
# In the consumer account (where EMR runs):
./scripts/bootstrap_consumer.sh --region us-east-1 \
--producer-account 111122223333

# In the producer account (which owns the data):
./scripts/bootstrap_producer.sh \
--consumer-role <ROLE_ARN from previous step>
Then, back in the consumer account, run the cross-account phase:
The result joins the producer account’s table to a local Iceberg table in a single query, with no data copy.
For the full cross-account policy setup (Lake Formation grants, AWS Glue resource policy, S3 bucket policy, and AWS KMS key policy), see the Cross-account setup section.
Tip: Add –dry-run to either bootstrap script to preview every action it would take (buckets, roles, policies, applications) without creating anything.
Clean up
To avoid ongoing charges, run the clean-up script or follow the steps in the repository README:
./scripts/cleanup.sh
This removes S3 data, AWS Glue databases and tables, Lake Formation permissions, and the Amazon EMR Serverless application.
Cross-account setup
Cross-account access requires configuration across four services. The following example shows the AWS Glue resource policy. The accompanying bootstrap_producer.sh script configures all four, so you don’t need to author each policy by hand.
1. AWS Lake Formation: Grant permissions on the database and tables to the consumer principal.
spark.sql.catalog.spark_catalog = RedirectingSessionCatalog (Delta and Hudi require additional spark.sql.extensions. See Quick start)
Analytics in one account, data in another
spark.sql.catalog.<name> pointing at the remote Glue account (see Multi-catalog section)
Many accounts, want zero upfront config
spark.sql.catalogResolver = GlueCatalogResolver
All of the above
All three. They compose.
Note: Multi-catalog is query-time resolution. It doesn’t copy data between accounts, replicate tables, or grant access. Cross-account reads still require Lake Formation grants, AWS Glue resource policies, Amazon S3 bucket policies, and (if encrypted) AWS KMS key policies.
Conclusion
In this post, we configured the RedirectingSessionCatalog as the default Spark catalog on Amazon EMR 8.1.0. With a single configuration property, the RSC resolved Iceberg, Delta Lake, Hudi, and Hive tables through one catalog without format-specific prefixes. We then declared a named catalog to join tables across two AWS accounts, and enabled the GlueCatalogResolver to discover remote catalogs at query time without pre-declared spark.sql.catalog.* properties.
Multi-catalog support is available on Amazon EMR 8.1.0 across all deployment models: Amazon EMR Serverless, Amazon EMR on EC2, and Amazon EMR on EKS. To reproduce the walkthrough, clone the aws-samples/aws-emr-utilities repository and follow the steps in the Quick start section.
To learn more and get started, explore the following resources:
Amazon Redshift has progressively deepened its integration with Apache Iceberg. Earlier this year we launched Amazon Redshift RG, powered by AWS Graviton, with a purpose-built, integrated vectorized query engine designed from the ground up for data lakes. Instead of sending scans to a separate fleet, RG runs them natively on the cluster using vectorized Parquet scans, a smart-prefetch I/O subsystem, partition- and file-level pruning, improved bloom filters, and automatic Iceberg statistics collection through JIT Analyze for better query plans. Together, these deliver up to 2.4x faster Apache Iceberg queries than RA3, at 30 percent lower cost per vCPU and with no per-terabyte scan charges on data lake queries. On top of that performance foundation, you can write directly to Iceberg tables with full ACID alignment using INSERT, CTAS, UPDATE, DELETE, and MERGE. You can govern access with AWS Identity and Access Management (IAM) permissions through the external schema’s IAM role or with AWS Lake Formation for fine-grained, cross-engine control.
Amazon Redshift now also supports creating and refreshing Iceberg materialized views. A materialized view (MV) pre-computes expensive joins and aggregations once and stores the result as a standard Apache Iceberg table in Amazon Simple Storage Service (Amazon S3) or Amazon S3 Table Buckets, registered in the AWS Glue Data Catalog. You create one using familiar SQL (CREATE MATERIALIZED VIEW ... USING ICEBERG), and the result is instantly queryable by Iceberg-compatible engines, including Amazon Athena, Apache Spark on Amazon EMR, and AWS Glue. Amazon Redshift keeps it current with incremental refresh, and because the result is an ordinary Iceberg table in the AWS Glue Data Catalog, it is governed and discovered like any other catalog table.
Consider a team that runs its analytics on Amazon Redshift. Their transformations are already written in Amazon Redshift SQL, their staff know Amazon Redshift, and they’ve invested in its query engine. What they don’t have is a way to share their most expensive pre-computed results with the other engines in their organization, such as a data science group on Spark or an ad-hoc reporting team on Athena, without exporting copies or standing up a second transformation stack. The gap for this team is that they want interoperability and acceleration from the engine they already run.
Now they can create this materialized view in Amazon Redshift, in the SQL they already write, and Amazon Redshift stores the pre-computed result as an open Iceberg table. The Spark and Athena teams read that same result directly, without maintaining copies or separate pipelines. As new data lands, incremental refresh recomputes only what changed. The team gets a single, consistent source of truth for its most expensive queries that every engine shares. The Amazon Redshift team can run an end-to-end transformation pipeline in one engine, using materialized views as the building block between raw, cleaned, and serving layers without stitching multiple engines together stage by stage.
And you don’t need to choose between open and fast: for your most latency-sensitive dashboards, you can still load these Iceberg materialized views into Amazon Redshift Managed Storage (RMS) as native RMS materialized views.
When to use Iceberg MVs compared to Amazon Redshift (RMS) materialized views
Iceberg materialized views don’t replace the standard materialized views of Amazon Redshift. They serve a different need. Amazon Redshift materialized views store their results in Amazon Redshift Managed Storage (RMS), which is highly optimized for fast reads from Amazon Redshift. Iceberg materialized views store their results as open Iceberg tables in your Amazon S3, readable by your choice of engine. Choose based on where and how the result is consumed:
Use Amazon Redshift (RMS) materialized views when:
You query only from Amazon Redshift.
You need the lowest read latency. For interactive dashboards and sub-second lookups, reading from RMS is significantly faster than reading an Iceberg table from Amazon S3.
You want the most straightforward option for an Amazon Redshift-only workload.
Use Iceberg materialized views when:
You want the pre-computed result readable by engines beyond Amazon Redshift (Athena, Spark, Amazon SageMaker AI, third-party engines) without copying data.
You’re standardizing on Apache Iceberg for interoperability and don’t want acceleration tied to an Amazon Redshift-only storage format.
You want to run an end-to-end pipeline in a single engine and have every downstream consumer share the same open result.
They’re complementary. A common pattern is to build and transform data as Iceberg materialized views for openness and cross-engine access, then load the most performance-sensitive results into an RMS materialized view for your hottest interactive dashboards. This keeps your data open by default and fast where it counts.
In this post, you will:
Understand why Iceberg materialized views matter and their key use cases.
Learn how incremental refresh and cross-engine access work.
Set up prerequisites (IAM, Amazon S3, AWS Glue).
Create your first Iceberg materialized view.
Verify cross-engine access from Amazon Athena and PyIceberg.
This solution uses the following AWS services:
Amazon Redshift (Serverless or RG provisioned).
AWS Glue Data Catalog.
Amazon S3 (general purpose buckets or Amazon S3 Tables).
AWS Identity and Access Management (IAM).
AWS Lake Formation (optional, for governed access).
Solution overview
With Iceberg materialized views, you can compute aggregations once in Amazon Redshift and store the results as standard Apache Iceberg tables in Amazon S3 or Amazon S3 Table buckets. Iceberg-compatible engines can then query these pre-computed results directly.
Figure 1: Iceberg-compatible engines query the pre-computed materialized view directly from Amazon S3
Powered by Amazon Redshift Serverless and Amazon Redshift RG
Iceberg materialized views are supported on:
Amazon Redshift Serverless – Fully managed, auto scaling compute. Recommended for variable workloads where MV refreshes run alongside one-time queries without capacity planning.
Note: Amazon Redshift RA3 and DC2 instance types don’t support Iceberg materialized views.
Amazon Redshift does the heavy computation once on Serverless or Provisioned RG instances. Every Iceberg-compatible engine (Athena, Spark, SageMaker, and AWS Glue) consumes the pre-computed Iceberg MV from Amazon S3 or Amazon S3 Tables at standard Amazon S3 read cost. No additional compute charges on the consumer side.
Use cases
Iceberg materialized views support several patterns across analytics, cost optimization, and AI workloads.
1. Medallion architecture with shared optimization
The problem: In Bronze→Silver→Gold architectures, optimizations at silver/gold layers benefit only the engine that computed them.
With Iceberg MVs: Amazon Redshift RG computes silver and gold layers as Iceberg MVs with incremental refresh. Output is standard Iceberg on Amazon S3, so every consumer benefits without additional compute.
2. Empowering agentic AI, feature stores, and generative AI workloads
The problem: AI agents, machine learning (ML) pipelines, and generative AI applications need pre-computed features, such as rolling averages, customer lifetime value, and engagement scores, in a format frameworks can consume without direct warehouse connectivity.
With Iceberg MVs: The heavy computation (complex joins, window functions, statistical aggregations) runs once on Amazon Redshift Serverless or RG. Materialized views that use window functions or aggregations beyond COUNT and SUM are fully recomputed on each refresh rather than incrementally updated. Once the materialized view is computed and stored in Amazon S3 as a standard Iceberg table, it can be accessed by different consumers natively:
Amazon SageMaker notebooks and training jobs read features directly from Amazon S3 through PyIceberg, with no JDBC driver needed.
Amazon Bedrock agents access pre-computed analytics as structured data for Retrieval Augmented Generation (RAG).
Apache Spark on Amazon EMR consumes features through spark.table() for large-scale ML training pipelines.
Amazon Athena provides serverless SQL access to materialized features for ad-hoc analysis and dashboarding.
3. Cost optimization through compute consolidation
The problem: When the same aggregation is re-executed independently across multiple engines (Amazon Redshift, Athena, Spark, third-party tools), organizations pay for redundant compute on each engine, which multiplies cost linearly with the number of consumers.
With Iceberg MVs: One Amazon Redshift Serverless or RG refresh computes the aggregation once. Consumers read the pre-computed result directly from Amazon S3 at standard storage read cost, alleviating redundant compute across engines. The cost reduction can scale with the number of consuming engines you consolidate.
4. Governed data sharing without data movement
The problem: Sharing analytics across teams requires data copying or engine-specific sharing mechanisms.
With Iceberg MVs: Output is governed by AWS Lake Formation. Grant access with a single permission model. Consumers bring their preferred engine.
5. Single source of truth across analytics engines
The problem: Multiple teams recompute the same metrics independently across Spark, Amazon Redshift, Athena, and custom tools, producing inconsistent numbers.
With Iceberg MVs: One CREATE MATERIALIZED VIEW ... USING ICEBERG computes the metric once on Amazon Redshift Serverless or RG. Every engine reads the same Iceberg table from Amazon S3, with the same numbers, the same snapshot, and zero reconciliation.
How it works
Iceberg MVs extend the native materialized view capability of Amazon Redshift with the USING ICEBERG clause:
CREATE MATERIALIZED VIEW awsdatacatalog.analytics.daily_revenue
USING ICEBERG
LOCATION 's3://amzn-s3-demo-analytics/daily_revenue/'
PARTITIONED BY (day(order_date))
AS
SELECT order_date, region,
       SUM(amount) AS total_revenue, COUNT(*) AS transaction_count
FROM awsdatacatalog.source.transactions
GROUP BY 1, 2;
The MV can also be stored in Amazon S3 Table Buckets. If you omit the LOCATION clause, Amazon S3 Tables manages storage automatically.
Incremental refresh
Amazon Redshift tracks Iceberg snapshot IDs across refreshes. On REFRESH MATERIALIZED VIEW, it identifies changed source partitions and recomputes only the delta.
Set operations (UNION ALL, UNION, INTERSECT, EXCEPT).
MIN, MAX, AVG, COUNT(DISTINCT), SUM(DISTINCT).
GROUPING SETS, ROLLUP, CUBE.
Cross-cluster refresh
The MV isn’t tied to the creating cluster. Amazon Redshift clusters or Serverless workgroups with the appropriate IAM role can refresh it. When multiple clusters attempt to refresh the same MV concurrently, Amazon Redshift coordinates through the AWS Glue Data Catalog to make sure that only one refresh succeeds at a time, helping prevent conflicts automatically. For more details on concurrency handling, see the Amazon Redshift Iceberg materialized views documentation.
Cross-engine access
The result is a standard Iceberg table that needs no special drivers. This materialized view can be read from different engines, as shown in the following examples:
Amazon Athena:
SELECT * FROM analytics.daily_revenue WHERE region = 'us-east';
Why are these two principals? Amazon Redshift needs to assume the role to perform materialized view operations. AWS Glue needs to check base table permissions on behalf of the materialized view definer role.
Step 2: Attach IAM policies
Attach the following scoped inline policies to the IcebergMvDefiner role. These provide the minimum permissions required for Iceberg materialized view operations.
Create an S3 bucket for MV storage. We recommend the naming convention iceberg-mv-. Enable default encryption (SSE-S3) and block all public access.
Step 4: Create AWS Glue database
Create a database named iceberg_mv in the AWS Glue Data Catalog. Use a plain create-database command. The database inherits IAM_ALLOWED_PRINCIPALS by default, which allows cross-engine access from Amazon Athena and other engines.
Step 5: Associate role with Redshift
Associate the IcebergMvDefiner role with your Amazon Redshift cluster or Serverless namespace:
With prerequisites in place, you can now create an external schema, a base Iceberg table, and your first materialized view.
Step 7: Create external schema
CREATE EXTERNAL SCHEMA iceberg_schema FROM DATA CATALOG DATABASE 'iceberg_mv' REGION '<<your-region>>' IAM_ROLE 'arn:aws:iam:::role/IcebergMvDefiner';
Step 8: Create Iceberg base table with sample data
CREATE TABLE iceberg_schema.orders USING ICEBERG LOCATION 's3://<<your-bucket>>/iceberg_mv_blog/orders' AS SELECT 1 AS id, 'us' AS region, 100 AS amount UNION ALL SELECT 2, 'eu', 200 UNION ALL SELECT 3, 'jp', 150;
Step 9: Create the Iceberg materialized view
CREATE MATERIALIZED VIEW iceberg_schema.sales_by_region USING ICEBERG LOCATION 's3://<<your-bucket>>/iceberg_mv_blog/sales_by_region' AS SELECT region, SUM(amount) AS total, COUNT(*) AS num_orders FROM iceberg_schema.orders GROUP BY region;
Step 10: Verify MV contents
SELECT * FROM iceberg_schema.sales_by_region;
Figure 2: Initial materialized view query results aggregated by region
Step 11: Test incremental refresh
Insert new rows into the base table and refresh the MV:
INSERT INTO iceberg_schema.orders VALUES (4, 'us', 300), (5, 'eu', 50);
REFRESH MATERIALIZED VIEW iceberg_schema.sales_by_region;

SELECT * FROM iceberg_schema.sales_by_region;
Figure 3: Materialized view query results after inserting new rows and refreshing
Cross-engine verification
The materialized view is now a standard Iceberg table in the AWS Glue Data Catalog, accessible from compatible engines without an Amazon Redshift connection.
Amazon Athena:
SELECT * FROM iceberg_mv.sales_by_region WHERE region = 'us';
Figure 4: Querying the materialized view from Amazon Athena
If your organization requires centralized access control across engines, you can layer AWS Lake Formation governance on top of the IAM-only setup. Note that Lake Formation permissions for Iceberg MVs are coarse-grained (database and table level). Fine-grained access control (row filters, column filters) isn’t supported on Iceberg materialized views. The following additional steps were validated in the same environment used in this walkthrough:
Add lakeformation.amazonaws.com to the IAM role trust policy (in addition to redshift.amazonaws.com and glue.amazonaws.com).
Add lakeformation:GetDataAccess to the role’s inline policy.
Register the S3 bucket as a Lake Formation data location:
Grant Lake Formation permissions to the definer role: DATA_LOCATION_ACCESS on the S3 bucket, CREATE_TABLE/DESCRIBE/ALTER/DROP on the database, and ALL on tables (with grant option).
To avoid incurring ongoing charges, remove the resources created in this walkthrough:
DROP MATERIALIZED VIEW iceberg_schema.sales_by_region;
DROP TABLE iceberg_schema.orders;
DROP SCHEMA iceberg_schema;
Note:DROP MATERIALIZED VIEW removes the AWS Glue catalog entry but does not delete the underlying data in Amazon S3. To remove the data, delete the Amazon S3 prefix manually:
Iceberg materialized views take the open lakehouse promise further: optimization itself becomes portable. Amazon Redshift, whether running as Serverless or on RG instances powered by AWS Graviton, does the heavy computation once. Every other engine and ML pipeline benefits without additional compute. Start with one MV. Watch the numbers match across engines for the first time. Then scale from there.
Resources
Getting started with Iceberg materialized views (Amazon Redshift documentation)
As AI models become more capable, they uncover more security vulnerabilities and identify increasingly sophisticated paths to exploit them, raising the bar for how quickly defenders must respond. Security teams now face more potential vulnerabilities than their existing processes were designed to handle — each requiring investigation, reproduction, and a repair that must be tested to confirm it closes the vulnerability without breaking expected behavior.
AWS Continuum for code vulnerabilities accelerates this work with autonomous security at machine speed. To measure Continuum against a concrete public standard, we chose CyberGym-E2E, which asks an agent to find a vulnerability in a real codebase, demonstrate it with a working proof of concept, and repair it without breaking behavior covered by the project’s tests. Continuum passed 819 of 920 tasks within the benchmark’s 90-minute limit, achieving an 89.0% end-to-end success rate. This establishes a new standard 23.1 percentage points up from the previous public high of 65.9%.
Measuring the full vulnerability lifecycle
Many security benchmarks test a single task in isolation. Detection benchmarks test whether a system can identify suspicious code, while patching benchmarks begin with a known flaw and ask for a fix. CyberGym, the predecessor to CyberGym-E2E, also begins with a known vulnerability and focuses on exploit generation. By contrast, CyberGym-E2E evaluates the full vulnerability lifecycle, requiring a system to identify and demonstrate a vulnerability before producing a tested repair. This broader scope more closely reflects the work facing security teams.
Each CyberGym-E2E task places an agent in a container with a vulnerable revision of a real open-source project and the tools needed to build and test it. An agent can inspect and modify the source, but receives no vulnerability description, proof of concept, crash log, or original patch. External network access is blocked, and protected benchmark files cannot be modified. Within 90 minutes, the agent must submit an input demonstrating a vulnerability and a source-code patch. The full benchmark contains 920 tasks based on historical OSS-Fuzz vulnerabilities across 139 open-source projects. The median project contains more than 600,000 lines of code.
The benchmark evaluates each submission in four cumulative stages:
S1 checks whether the agent produced an input that crashes the vulnerable program.
S2 checks whether the agent’s patch prevents that crash.
S3 checks whether the patched project still passes its functionality tests.
S4 checks whether the patch also fixes the specific historical vulnerability selected by the benchmark.
CyberGym-E2E defines S3 as its main measure of end-to-end success. S4 is diagnostic because a repository may contain several valid vulnerabilities: an agent can find and repair a real flaw that differs from the benchmark’s selected target.
Continuum sets a new standard
Continuum for code vulnerabilities reached a new standard for every stage of CyberGym-E2E. The table below compares its performance with the previous best public results.
Stage
What it measures
Continuum
Previous public high
Difference
S1
Finds and reproduces a vulnerability
92.5%
67.9%
+24.6%
S2
Repairs its generated crash
89.6%
66.2%
+23.4%
S3
Preserves tested functionality
89.0%
65.9%
+23.1%
S4
Also repairs the benchmark’s selected vulnerability
37.8%
26.2%
+11.6%
On S3, the benchmark’s main measure of end-to-end success, Continuum passed 819 of 920 tasks. Its 89.0% success rate exceeds the previous public high of 65.9% by 23.1 percentage points. The result reflects both the capability of the underlying frontier models and Continuum’s design as a multi-agent security system. The next section examines how that system adds value beyond the models alone.
The official 89.0% result applies CyberGym-E2E’s 90-minute limit. When tasks were allowed to continue beyond that limit, Continuum’s end-to-end pass rate reached 93.7%, indicating higher potential coverage when longer-running analyses can complete.
We conducted the evaluation under CyberGym-E2E’s network-isolation and submission-review requirements. External retrieval was blocked during execution, and post-run trajectory review confirmed that successful results came from vulnerability analysis rather than retrieval of public historical fixes.
Harness design for end-to-end security
Continuum for code vulnerabilities is a multi-agent system organized around the main phases of the code vulnerability lifecycle: discovery, validation, and remediation. Each phase uses specialized agents adapted to the evidence and decisions it requires. The system carries evidence forward so that each phase builds on the work completed before it.
During discovery, Continuum analyzes the repository and develops candidate vulnerability findings. Its agents identify code paths that warrant deeper investigation and record the source evidence supporting each candidate.
During validation, specialized agents attempt to turn a candidate finding into a demonstrated security issue. They construct a proof of concept, run it against the vulnerable program, and determine whether the observed behavior supports the finding. This converts a potential code-level weakness into executable evidence.
During remediation, agents trace the vulnerability to its root cause and produce a patch. Continuum then verifies that the patch prevents the demonstrated failure and that the project’s functionality tests continue to pass. The repair is therefore evaluated against the same evidence used to establish the vulnerability.
Together, these phases create a connected record from suspicious code to a demonstrated vulnerability and tested repair. The architecture allows Continuum to adapt its tools, instructions, checks, and models to each phase while maintaining a consistent standard of evidence. It also supports a multi-model approach that can leverage complementary strengths and incorporate new models as they become available.
In customer environments, Continuum can also combine code-level evidence with available deployment context, including service exposure, network paths, permissions, and configuration. This context helps distinguish vulnerabilities with limited production impact from exposures that demand immediate action. CyberGym-E2E evaluates the code-level process but does not provide deployment context, placing this broader prioritization capability outside the benchmark’s scope.
Beyond CyberGym-E2E
CyberGym-E2E advances security evaluation by turning a complex, multi-stage process into a large public benchmark with reproducible tasks and outcomes that can be verified by running code. The CyberGym-E2E authors’ careful work on task construction, scoring, and submission standards gives the field a concrete foundation for measuring end-to-end progress.
To keep evaluation consistent and reproducible across 920 tasks, CyberGym-E2E focuses on memory-safety vulnerabilities in C and C++ projects. Sanitizer-detected crashes provide objective evidence of a defect, while subsequent checks determine whether a repair blocks the proof of concept and preserves functionality covered by the project’s tests. This design necessarily leaves many languages and vulnerability classes outside the benchmark’s current scope, including many of the most common and impactful bug classes observed in production systems. Evaluating these areas will require different task environments and equally rigorous forms of validation.
Our view of end-to-end security also extends beyond producing a tested code-level repair. In production systems, deployment context such as service exposure, network paths, permissions, and configuration often determines whether a vulnerability presents limited risk or demands immediate action. Future evaluations should test whether autonomous systems can reason about this context and prioritize findings according to their effect on the safety of the deployed system.
CyberGym-E2E’s value extends beyond the dataset itself. It makes the case that end-to-end security is worth defining and measuring as a task in its own right. That involves hard design choices about scope, evidence, and what counts as success, and CyberGym-E2E gives the field a concrete starting point for working through those choices. This system-level view complements our work on the Deception Benchmark, which evaluates a narrower but related capability: how reliably individual frontier models distinguish real vulnerabilities from safe code. Together, they examine security performance at both the model and system levels.
To learn how AWS Continuum for code vulnerabilities helps teams discover, validate, prioritize, and remediate vulnerabilities at machine speed, visit the AWS Continuum product page.
Tags are an important and versatile tool on AWS. FinOps teams track costs with them, security teams enforce compliance, and governance teams gate access through attribute-based access control (ABAC).
Tags become especially important as infrastructure management grows more complex across multiple accounts in an organization. Because compute is a common shared resource, many organizations tag their AMIs to track approval status, OS versions, and team. However, when you share an AMI with another AWS account, the tags you attached to it stay behind. The other account sees the image, but tag metadata used to describe it could not be shared.
Until today, the only way to solve this was to build a custom workflow to copy tags into every account the AMI is shared with. Typically created with services such as AWS Simple Notification Service (Amazon SNS) and AWS Lambda, this caused operational burden.
Today, we’re introducing EC2 Tag Sharing, a new feature that AMI owners can use to share tags with any account that has access to the image. Whether an AMI is shared with an account, across an organization, or made public, a shared tag is automatically shared alongside the image by adding the ec2:SharedTag/ prefix to the tag key. Updates also propagate automatically without any need for custom replication workflows. In this post, we walk through how tag sharing works, demonstrate a common use case, and cover considerations and best practices.
How it works
Any tag whose key starts with ec2:SharedTag/ is visible to all AWS accounts the AMI is shared with, and also when the AMI is shared publicly. Tags without the prefix remain private to the account that created them, exactly as they do today.
Only the resource owner can create, modify, or delete tags with the ec2:SharedTag/ prefix. Accounts you share the AMI with can view these tags but cannot change them. They can continue to add their own private tags to a shared AMI.
Shared tags count against the resource owner’s 50-tag-per-resource quota for both shared and private tags. They do not count against the quota of accounts you share the image with. When you copy an AMI that has shared tags, AWS Elastic Compute Cloud (AWS EC2) copies the shared tags to the new image when the --copy-image-tags parameter is included. At launch, tag sharing is supported specifically for AMI resources.
Creating a shared tag (CLI)
To share a tag, create it with the ec2:SharedTag/ prefix on the key name. For example, to share a tag indicating the AMI’s approval status:
You can add multiple shared tags alongside your private tags. In the following example, status and os-version are shared with other accounts. The team tag remains private to the owner.
To stop sharing a specific tag, delete the tag with the ec2:SharedTag/ prefix:
# Remove the shared tag
aws ec2 delete-tags \
    --resources ami-0abcdef1234567890 \
    --tags Key=ec2:SharedTag/status
If you want to keep the tag private, recreate it without the prefix:
# Optionally, recreate as a private tag
aws ec2 create-tags \
    --resources ami-0abcdef1234567890 \
    --tags Key=status,Value=approved
Viewing shared tags as a recipient
When an AMI is shared with your account, you can see the shared tags alongside any tags you’ve added yourself. Figure 1 shows an example of an AMI shared from the original account with both private and shared tags. Figure 2 shows that AMI in the recipient account. The ec2:SharedTag/ prefix in the key name makes it clear which tags came from the owner.
Figure 1: AMI tags in the originating account, showing both private and shared tags
Figure 2: The same AMI in the recipient account, where only the shared tags are visible
As you can see in the preceding figures, the shared tags are visible across both accounts. However, the private tags created in the original account are only visible in the original account.
A common use case: Golden AMIs
Many organizations maintain a central build factory account that produces hardened, security-approved AMIs. These golden images can be shared with hundreds or thousands of workload accounts across an organization. Tags like status=approved or patch-date=2026-09-18 are commonly used by recipient accounts to enforce policies that only allow launches from approved images.
Before tag sharing, the build factory had to replicate tags to every account the AMI is shared with after each AMI publish. A typical workflow looked like this:
The build factory creates a new AMI and tags it.
An SNS notification triggers a Lambda function in each account.
Each Lambda function reads the tag values from the AWS SNS message and calls CreateTags on the shared AMI in its own account.
Because this runs for every AMI, in every Region, across every account, the number of CreateTags API calls can grow rapidly in concentrated bursts. At that scale, teams risk throttling, failed Lambda invocations, and tag drift when calls silently fail.
With tag sharing, the build factory tags the AMI with the ec2:SharedTag/ prefix. Every account the AMI is shared with sees these tags, without the need for additional pipelines to replicate the tags. When the build factory updates a tag (for example, marking an older image as deprecated), the change is visible across all accounts without any additional API calls.
Considerations
Shared tags are visible to every account with access. We recommend that you do not include personally identifying, confidential, or sensitive information in these tags.
If consuming accounts have ABAC policies that evaluate tags, those policies will also apply to the shared AMI. For example, if a recipient account has a policy that allows ec2:RunInstances only when the AMI has the tag status=approved, and you share that tag by using ec2:SharedTag/status=approved, the policy will deny it.
When you adopt the shared tags model, any action that depends on those tags is controlled by the AMI owner, not by the recipient account. This includes tag-gated instance launches, AWS Identity and Access Management (IAM) and ABAC policy evaluations, and any downstream automation that reads tag values. Because only the owner can create, modify, or delete shared tags, the recipient account cannot change the values its own policies depend on. Before you rely on a shared tag in a policy or workflow, make sure you trust the owner account to set and maintain that value.
As a best practice, apply account-level governance so that you only consume AMIs from providers you trust. With Allowed AMIs, you can define criteria for which AMIs are allowed in your account, for example a list of trusted AMI provider account IDs. Only AMIs that meet the criteria are discoverable and available to launch in your account. To preview the impact before enforcing, start in audit mode.
Conclusion
EC2 Tag Sharing removes the need to build and maintain cross-account tag replication workflows. For organizations that share AMIs, this means less undifferentiated heavy lifting. To get started, add a tag with the ec2:SharedTag/ prefix to a shared AMI in the AWS EC2 console. To learn more, see Tag your AWS EC2 resources in the Amazon EC2 User Guide.
Operators often restart fleets when they need to pick up runtime configuration changes, recover unhealthy processes, or return hosts to a known state. Before RESTART, AWS CodeDeploy customers either redeployed the current revision, repeating completed work, or ran custom scripts outside of CodeDeploy production safeguards. Now there’s a purpose-built option: RESTART deployment mode. It keeps the operation inside CodeDeploy, so you get the same batch sizing, health checks, alarm monitoring, and rollback behavior as a standard deployment.
This new option reapplies the last successful revision to Amazon Elastic Compute Cloud (Amazon EC2) and on-premises in-place deployments. It retains your deployment configurations, lifecycle hooks, Amazon CloudWatch alarm monitoring, rollback settings, and deployment history.
In testing, a fleet restart completed up to 6.1x faster than a standard deployment, turning a multi-minute rollout into tens of seconds.
In this post, we explain how RESTART works, walk through starting a restart deployment from the command line and the CodeDeploy console, and review the safety controls that carry over from a standard deployment.
Why use a CodeDeploy restart?
A restart changes production even when the application revision stays the same. Hosts stop and start, failures reduce fleet capacity, and external configuration errors spread across restarted hosts. Fleet scripts must recreate batch sizing, minimum healthy capacity, validation, alarm monitoring, and audit history. One customer experienced this firsthand. Their restart script restarted hosts in batches with no health checks in between. When a bad configuration left the first batch unable to start, the script never noticed and continued. What should have been a routine restart took down their fleet.
This new deployment mode keeps the operation in CodeDeploy. You configure how the deployment runs with the familiar CreateDeployment API. CodeDeploy still runs your lifecycle hooks, validates the result, and stops after a health or alarm breach. A failed restart stays within the active batch instead of continuing through the fleet.
RESTART also works well as a building block for automated remediation. Point a CloudWatch alarm on a memory or resource-utilization metric at an Amazon EventBridge rule, and have that rule invoke an AWS Lambda function that calls CreateDeployment with deploymentMode: RESTART. Long-running or stateful workloads benefit from periodic recycling. Examples include self-managed Kafka brokers and JVM services with memory growth. This turns that recycling into a managed, self-healing loop instead of a cron job or a manual restart. The following diagram shows the flow:
Figure 1: Automated remediation loop using an Amazon CloudWatch alarm, an Amazon EventBridge rule, and an AWS Lambda function to trigger a RESTART deployment
How RESTART works
Set deploymentMode to RESTART on CreateDeployment and provide no revision. CodeDeploy resolves the deployment group’s last successful revision and creates a deployment record.
CodeDeploy agents that support local reuse (from version 2.1.0 onward) use the previous deployment’s archive. DownloadBundle remains in the signed workflow. If the archive is unavailable or invalid, the agent downloads the same pinned revision, covering added or replaced hosts.
Install reapplies the revision and corrects drift in managed files. BeforeInstall, AfterInstall, and ValidateService run as defined in the AppSpec file. Local reuse removes the network transfer, and end-to-end savings vary with revision size, agent version, hooks, fleet size, and deployment configuration.
Performance in feature testing
Feature tests peaked at 6.14x. Tests used m5.large instances, a 1 GB revision, and 10, 50, and 100-host fleets with and without an Application Load Balancer (ALB). Each scenario ran seven times. We discarded the minimum and maximum and report the median of five. Results combine local reuse with omitted traffic control and are not predictive of results for other applications.
At 75 percent minimum healthy, four or five waves saved ALB-backed fleets 397.1 to 424.8 seconds. The 50-host fleet reached 6.14x.
Host Count
ALB in Front?
Rollout Waves
Standard Deployment Time
Restart Deployment Time
Speedup
Time Saved
10
Yes
5
526.2s
129.1s
4.08x
397.1s
50
Yes
5
507.4s
82.6s
6.14x
424.8s
100
Yes
4
544.5s
144.7s
3.76x
399.8s
10
No
5
192.4s
167.8s
1.15x
24.6s
50
No
5
190.5s
117.2s
1.63x
73.3s
100
No
4
260.8s
139.6s
1.87x
121.2s
With two-wave HalfAtATime, ALB-backed fleets saved 168.6–185.7 seconds. No-ALB rows isolate local reuse.
Host Count
ALB in Front?
Standard Deployment Time
Restart Deployment Time
Speedup
Time Saved
10
Yes
230.2s
61.6s
3.74x
168.6s
50
Yes
276.2s
90.5s
3.05x
185.7s
100
Yes
275.2s
103.9s
2.65x
171.3s
10
No
133.8s
37.0s
3.62x
96.8s
50
No
152.4s
86.7s
1.76x
65.7s
100
No
162.7s
109.1s
1.49x
53.6s
Multi-wave ALB deployments repeated traffic control and saved the most time. These results carry a couple of safety implications to keep in mind.
The safety controls remain familiar
A RESTART deployment uses the controls already configured for the deployment group:
Deployment configuration: Use CodeDeployDefault.OneAtATime, CodeDeployDefault.HalfAtATime, CodeDeployDefault.AllAtOnce, or a custom minimum healthy host setting to bound concurrent restarts.
Lifecycle validation: CodeDeploy runs ValidateService on each host before it considers that host healthy.
CloudWatch alarms: CodeDeploy polls the alarms configured on the deployment group and stops the deployment when an alarm enters ALARM.
Automatic rollback: CodeDeploy applies the deployment group’s automatic rollback configuration for qualifying failures. A rollback can’t reverse an external configuration change, so correct the underlying configuration before retrying.
Deployment history:GetDeployment and ListDeployments expose the restart’s status, timestamps, revision, and result for monitoring and audit.
Traffic-control behavior
RESTART doesn’t run the load balancer BlockTraffic and AllowTraffic steps. The host remains registered while its application stops and starts. Treat this as an operational constraint, not as the reason to use RESTART.
For request-serving fleets, make ApplicationStop stop accepting new work and drain in-flight work before the process exits. Select a deployment configuration that preserves enough healthy capacity for the expected restart duration. Pull-based workers stop receiving work when the process stops, but their hooks still need to handle in-flight jobs safely.
Walk through a restart deployment
This section walks through starting a restart deployment from the command line and the CodeDeploy console, and then monitoring its progress.
Prerequisites
An existing Amazon EC2 or on-premises application and deployment group with at least one successful deployment.
An AWS Command Line Interface (AWS CLI) or SDK version that supports the deploymentMode request field.
CodeDeploy agent version 2.1.0 or newer on target hosts to benefit from local revision reuse. Earlier agents work but fall back to downloading the revision.
Start a restart deployment with the AWS CLI
The following command restarts the fleet with the deployment group’s default deployment configuration:
To restart one host at a time, provide a deployment configuration in the request:
aws deploy create-deployment \
    --application-name MyApp \
    --deployment-group-name MyDeploymentGroup \
    --deployment-mode RESTART \
    --deployment-config-name CodeDeployDefault.OneAtATime \
    --description "Restart one host at a time"
Omit --deployment-config-name to use the deployment group’s configured default.
Start a restart deployment on the console
You can also use this feature in the CodeDeploy console. Under Applications, select the deployment group you want to restart and choose Create deployment.
Figure 2: Choosing Create deployment for a deployment group in the CodeDeploy console
For Deployment mode, select Restart, and configure any other settings or overrides on the page (the same options you would set with the AWS CLI).
Figure 3: Selecting Restart as the deployment mode on the Create deployment page
Monitor the restart
You can see the status of the deployment on the console, or use the deployment ID with the GetDeployment API or CLI command. For example:
The deployment moves through the standard Created, InProgress, and terminal states. If a lifecycle hook fails, the deployment breaches its minimum healthy host requirement, or a configured alarm enters ALARM, CodeDeploy stops the restart and applies the configured failure behavior.
You can distinguish restart deployments by the deploymentMode field in the GetDeployment API, or visually on the console under Deployment details.
Figure 4: Deployment details showing the deploymentMode field set to RESTART
Handle alarms during incident recovery
If an alarm is already in ALARM state, CreateDeployment still creates the deployment. CodeDeploy then stops it when the deployment workflow observes that alarm during polling. The ignorePollAlarmFailure setting does not ignore an alarm in ALARM. It only controls behavior when CodeDeploy cannot retrieve alarm state.
If an approved incident runbook requires a restart despite the current alarm state, override alarm monitoring for that deployment:
This override disables all deployment-group alarms for that deployment. It requires codedeploy:UpdateDeploymentGroup in addition to the permission to create a deployment. Use it only when your incident process provides another health signal and explicitly authorizes the override. The deployment configuration and lifecycle validation continue to apply.
Request constraints
RESTART has the following constraints:
It supports EC2 and on-premises in-place deployment groups. It doesn’t support Amazon Elastic Container Service (Amazon ECS) or AWS Lambda deployment groups.
The deployment group must have a successful revision for CodeDeploy to reapply.
Don’t provide revision, s3Location, gitHubLocation, or deploymentRevisions. CodeDeploy resolves the revision from deployment history.
Don’t combine RESTART with updateOutdatedInstancesOnly. That option selects hosts that aren’t running the target revision, which conflicts with restarting hosts on the current successful revision.
Restarting a fleet is routine, but it still changes production availability and exposes configuration or process failures. RESTART gives the operation a first-class CodeDeploy path instead of requiring a separate fleet script.
Set deploymentMode to RESTART to reapply the deployment group’s last successful revision. CodeDeploy controls the batch size, runs the lifecycle hooks, validates each host, monitors configured alarms, records the result, and reuses the local revision archive when possible. The operation is faster when the archive is already present, while hosts that need to download it use the normal fallback path.
Amazon S3 Tables now support all data types in the Apache Iceberg V3 specification. You can create V3 tables or upgrade existing V2 tables to take advantage of V3 features like deletion vectors, row lineage, and new data types such as variant, nanosecond timestamps, unknown, geometry, and geography.
Apache Iceberg has become the open standard for managing large analytics datasets. It lets you manage petabyte-scale tables with features like schema evolution, hidden partitioning, and time travel queries, while keeping your data in open Parquet files in data lakes on object storage like Amazon S3. Amazon S3 Tables offer storage purpose-built to keep Iceberg tables performant and cost-effective as they grow, with fully managed features like automatic compaction, maintenance, replication, and Intelligent-Tiering.
Teams running analytics on Apache Iceberg V2 tables often hit the same limits as their data grows. A compliance request to delete 50,000 user records from a 2-billion-row table leaves behind positional delete files that slow queries until compaction runs. Semi-structured events land as JSON strings that every query has to parse. Geospatial coordinates and nanosecond-precision timestamps get encoded as strings or integers. Each workaround adds storage cost, query latency, and pipeline code. With V3, Iceberg solves these challenges by offering native support for semi-structured and geospatial data, faster row-level operations, and built-in row lineage for data governance.
Starting today, Amazon S3 Tables support all V3 data types, including variant, nanosecond timestamps, geometry, geography, and unknown, along with deletion vectors and row lineage. You can create new V3 tables or upgrade existing V2 tables in place, and S3 Tables continue to run compaction and maintenance for you.
Apache Iceberg V3
V3 is the latest version of the Iceberg specification. Among its many improvements, V3 introduces capabilities that address the most common pain points in V2. This includes:
Deletion vectors replace V2’s positional delete files with a compact binary format. That 50,000-row compliance delete now writes a single deletion vector file instead of thousands of small deletes, significantly reducing compaction time and delete file overhead.
Row lineage adds _row_id and _last_updated_sequence_number to each record automatically. Your downstream pipelines can query these fields to find changed rows without scanning the full table.
New data types let you store semi-structured, geospatial, and nanosecond-precision data natively instead of encoding it as strings or integers:
Nanosecond timestamp(tz) for nanosecond-precision timestamps
Geometry and geography for geospatial data
Unknown for columns with no known type
Variant data type stores semi-structured data in columnar format. During writes, the engine shreds variant data into hidden columns and collects statistics. At query time, those statistics enable file pruning that significantly reduces I/O compared to parsing JSON strings.
The following sections walk through how to use these V3 capabilities in practice, with examples that show how to create tables, work with the new data types, and manage data at scale.
Getting started
A retail analytics team tracks user behavior across web and mobile apps. Each event has a different structure: page views include URLs and duration, purchases include items and amounts, and searches include query terms and result counts. With V3’s variant type, you store all event shapes in one table without predefined schemas:
Now query the variant column directly, without PARSE_JSON at read time. With Amazon EMR Spark, use variant_get:
SELECT
  event_id,
  user_id,
  variant_get(payload, '$.action', 'string') AS action,
  variant_get(payload, '$.amount', 'double') AS amount
FROM my_catalog.namespace.clickstream
WHERE variant_get(payload, '$.action', 'string') = 'purchase'
  AND variant_get(payload, '$.amount', 'double') > 50.00
To enable deletion vectors for write operations, configure merge-on-read mode:
ALTER TABLE my_catalog.namespace.clickstream
SET TBLPROPERTIES (
  'write.delete.mode' = 'merge-on-read',
  'write.update.mode' = 'merge-on-read',
  'write.merge.mode' = 'merge-on-read'
)
Now when you run a compliance delete, V3 writes a small deletion vector instead of rewriting data files:
DELETE FROM my_catalog.namespace.clickstream
WHERE user_id = 'user-42'
S3 Tables compaction handles these deletion vector files automatically on the next maintenance cycle.
Upgrading from V2
AWS provides backwards compatibility for both versions to minimize disruption during migration to V3. Existing V2 readers continue to work on upgraded tables until you’re ready to fully adopt V3 features. For more details, see the S3 Tables Iceberg V3 documentation.
Upgrade an existing table atomically without rewriting data:
ALTER TABLE my_catalog.namespace.existing_table
SET TBLPROPERTIES ('format-version' = '3')
On the next compaction cycle, S3 Tables remove old V2 delete files. New modifications use deletion vectors automatically. Row lineage fields initialize on the first data modification after the upgrade.
This is a one-way operation. The Apache Iceberg specification does not support downgrading from V3 to V2. Verify that all engines accessing the table support V3 before upgrading.
Using row lineage for incremental pipelines
After your table has V3 data, use row lineage to build efficient incremental pipelines:
SELECT *, _row_id, _last_updated_sequence_number
FROM my_catalog.namespace.clickstream
WHERE _last_updated_sequence_number > 42
This returns only rows modified after sequence number 42. Your downstream jobs can checkpoint this value and process only new changes on each run, instead of scanning the full table.
Compatibility across AWS analytics services
AWS offers the broadest native Apache Iceberg support of any major cloud provider, with Iceberg-compatible services at every layer of the data stack: ingestion, storage, catalog, and analytics. You can store and automatically optimize V3 tables in Amazon S3 Tables, write data with Amazon EMR Spark, integrate and manage data with AWS Glue, and run analytics with Amazon Redshift. To learn more about AWS analytics support for V3, see the Apache Iceberg on AWS prescriptive guidance.
Both S3 Tables and AWS Glue Data Catalog support the Iceberg REST Catalog (IRC) API, enabling interoperability across engines regardless of the catalog endpoint.
The new V3 data types (variant, nanosecond timestamps, geometry, geography, and unknown) require an engine built on Apache Spark 4.0 or later, such as AWS Glue 6.0 or later, or Amazon EMR release 8.1 or later.
You can create V3 tables from the Amazon S3 console, AWS CLI, or any engine that supports the Iceberg REST Catalog API.
The new V3 data types are supported only for tables that use the Parquet file format (not ORC or Avro).
Columns of type variant, geometry, geography, or nanosecond timestamp can’t be included in a table’s sort order for compaction. Tables containing these columns still compact under the sort and Z-order strategies when the sort order uses columns of other types.
Now available
Amazon S3 Tables support for all Apache Iceberg V3 data types is now available in all AWS Regions where S3 Tables are supported. Apache Iceberg V3 support is available at no additional charge; standard S3 Tables pricing applies.
To get started, visit the Amazon S3 Tables documentation or create a table bucket from the Amazon S3 console. If you want to call APIs, search documentation, find regional availability, and check troubleshooting about this feature, try using the AWS MCP Server and plugins with your preferred AI tool. Send feedback to AWS re:Post or through your usual AWS Support contacts.
Today, we’re announcing metadata pre-filtering for Amazon S3 Vectors, which delivers higher recall on filtered queries by evaluating your metadata filter before the similarity search. You can filter on attributes such as tenant, category, status, or time, and pre-filtering adds prefix matching with $startsWith for paths, URLs, and hierarchical keys. Each vector carries up to 2 KB of filterable metadata, and a single query supports up to 100 filter constraints. There is no additional cost, no re-ingestion, and no change to your queries.
Most applications never search a whole index. They search the part of it that belongs to a particular user, account, or category, and they express that scope as a metadata filter. Semantic search, retrieval-augmented generation (RAG), and agentic applications all need the same thing from a filtered query: a similarity search that covers the vectors matching the filter, and returns the closest of them. With pre-filtering, a filtered query returns more of the relevant matches your index contains, giving you higher recall on filtered searches.
Common use cases
Pre-filtering applies wherever results have to be both relevant and correctly scoped:
Legal and professional services: A law firm or e-discovery platform searches documents scoped to a single client, and with $startsWith narrows further by matter number, folder path, or document ID prefix. A single client is a small share of a firm-wide archive, and filters this narrow are where pre-filtering improves recall most.
Financial services: An investment research platform searches analyst notes, filings, and call transcripts scoped by issuer, document type, and publication date.
Media and entertainment: A streaming service filters by content rating and regional licensing before the semantic search, finding similar titles restricted to G and PG content licensed in one territory.
Agentic applications: An agent working within a user’s session filters on fields such as owner, document set, and timestamp so its searches cover the material relevant to the task at hand. Higher recall means more of that material reaches the agent, which improves task reliability
How pre-filtering works
Each vector in an S3 Vectors index can carry application-defined metadata, and a query can filter on those fields.
Every vector index has an index mode. On an index whose index mode is ENHANCED, S3 Vectors resolves your filter first, then searches only the vectors that match. On an index whose index mode is CLASSIC, S3 Vectors performs the vector search and filter evaluation in tandem, validating each candidate vector against your filter as it searches. Existing indexes use CLASSIC until you update them.
Consider a support knowledge base of 8 million tickets, where an agent searches one customer’s history for a recurring error. If that customer accounts for 400 of those tickets, resolving customer_id first means the similarity search runs across all 400 of them, so the agent sees that customer’s prior occurrences. Before the index was updated, the same query drew its candidates from the full 8 million, and the result set contained fewer of that customer’s matching tickets.
On highly selective filters, pre-filtering returns up to 5x more of the matching vectors than the same query returned before on CLASSIC indexes.
Getting started
Before you start, make sure your IAM policy grants permissions for the new actions.
You can get started in three steps. The walkthrough below builds a small product-catalog index and runs a selective filter against it, the same pattern you would use for a multi-tenant RAG store or a document search scoped to one client.
The dimension must match the output size of your embedding model, and distance-metric should match how that model was trained (cosine is common for text embeddings). Second, write vectors with the PutVectors API, attaching up to 2 KB of filterable metadata to each vector:
Each vector carries the attributes your application filters on. In this example, tenant_id scopes results to a single customer, category narrows by document type, created_date records when the document was created, and active is a boolean flag. By default every metadata field is filterable, so you can query on any of them without declaring a schema up front.
Third, run a filtered similarity query with the QueryVectors API. The filter uses a compact JSON syntax where a bare key-value pair is an equality match, and operators such as $and, $or, and $gt combine or refine conditions. Pass --return-metadata so the query returns each vector’s metadata:
S3 Vectors first narrows the search space to vectors matching all three filter conditions, then returns the 50 most similar vectors from that subset. Because the filter is applied before the search, those results are drawn from across all the vectors that match it.
Prefix matching with $startsWith
Pre-filtering adds a prefix match operator for filtering on paths, URLs, and hierarchical keys. A document store that encodes case and folder structure into a document ID can scope a search to a subtree in one condition:
Pre-filtering takes effect in place. Your existing vectors are not re-ingested, your queries do not change, and the new filter operators are available immediately.
Here is the difference on the same index and the same query. Before the update, a query scoped to one tenant returns two of the ten results requested:
Once you have validated pre-filtering on an index, set the default index mode on the vector bucket so that new indexes use ENHANCED without a follow-up call:
To bring the rest of your existing indexes across, list them and check the index mode on each one, then call UpdateIndexMode on the ones still using CLASSIC:
Indexes created in vector buckets created on or after September 30, 2026 use index mode ENHANCED. Indexes in buckets that existed before that date use CLASSIC until you set the bucket default, including indexes created in those buckets afterward.
A single query supports up to 100 filter constraints, counted per value the filter evaluates. If a query exceeds that, you can usually consolidate the filter, replacing a 300-value $in over legal cases with a single caseId field, for example, or split it into smaller queries, run them in parallel, and merge the results by distance.
Get started today
Metadata pre-filtering is available at no additional cost in all commercial AWS Regions where Amazon S3 Vectors is available, and in the AWS China Regions. You pay standard S3 Vectors pricing for storage, PUT requests, and queries. For full pricing details, visit the Amazon S3 pricing page. For regional availability, visit Amazon S3 Vectors Regions and quotas.
Whether you’re scoping a RAG application to one tenant, scoping an agent’s searches to one user’s documents, or narrowing a catalog search to a licensing window, pre-filtering lets you apply those filters without trading away recall. To learn more and get started, visit the Amazon S3 Vectors documentation. Send feedback to AWS re:Post for S3 or through your usual AWS Support contacts.
Today, we’re announcing a new capability for Amazon Aurora PostgreSQL that you can use to directly query operational data together with data stored in your data lake in Apache Iceberg and Apache Parquet formats, using your existing PostgreSQL applications and tools. By eliminating the need to extract, transform, and load (ETL) structured data from data lakes into your operational database, you can reduce operational complexity and simplify application development. You can also use Aurora PostgreSQL to query data from data lakes managed in Iceberg REST Catalog (IRC)-compatible catalogs, giving you access to data across a breadth of analytics systems without moving or duplicating it. Whether you’re powering real-time dashboards, enriching transactions with historical context, or building AI agents that reason over both live and archived data, you can now do it all through a single, familiar interface.
Previously, if your application needed to combine recent transactional data in Aurora with historical records stored in Amazon S3, a common approach was to build reverse ETL pipelines that duplicated data, increased infrastructure costs, and required ongoing engineering effort to keep everything synchronized. This challenge only grows as you increasingly embed AI agents into your applications, where it is impractical to predict and pre-replicate every dataset an agent might need.
DuckLabs, the team that maintains the DuckDB project, recently joined Amazon, and this capability is an example of how the efficiency of DuckDB is being integrated into our services. DuckDB is now embedded directly within Aurora PostgreSQL, so you can query live operational data (including uncommitted writes) alongside your data lake in a single query. Query processing stays within Aurora, with no additional network hops and no ETL pipelines that duplicate data. You can query Apache Iceberg tables managed through the AWS Glue Data Catalog, as well as Parquet and Iceberg data stored in Amazon S3 and S3 Tables. You do all of this using familiar PostgreSQL syntax and your existing applications and tools.
We’re excited to bring the speed and simplicity of DuckDB directly into Aurora PostgreSQL, so you and your agents can query and combine operational and Iceberg data using the familiar PostgreSQL applications, tools, and endpoints already in use. By building this capability around DuckDB, future improvements to the open source engine can continue to bring performance and functionality gains to Aurora and other AWS services.
What is new
This capability is supported on two Aurora PostgreSQL major versions: 17 (starting with 17.11) and 18 (starting with 18.6). To use it, you create an Aurora PostgreSQL cluster, attach an IAM role with the AuroraAnalytics feature, and enable the aurora_analytics extension. The IAM role is what gives Aurora access to your data in Amazon S3 and the AWS Glue Data Catalog. You then create foreign tables that point to your Iceberg or Parquet data in the data lake, and query them using familiar PostgreSQL syntax. You can complete this setup through the Amazon RDS console, or with any PostgreSQL client such as psql. The process is well documented in the Aurora PostgreSQL documentation.
You can query data across external IRC-compatible catalogs through AWS Glue Data Catalog federation. You register the external catalog once with Glue, and then create foreign tables for the tables you want to query, the same way you would for any Glue-native table. A single query can then join data stored in Aurora with Iceberg tables registered across multiple catalogs, so applications get a unified view without moving data or replacing your existing catalog investments.
Aurora also applies optimizations such as predicate pushdown and column pruning so that only the relevant data is read. This keeps queries efficient even as the underlying data grows. Frequently accessed data is also cached in your Aurora instance, so subsequent queries against the same data return faster. You can inspect this behavior per query using aurora_analytics_stat_statements(), which reports metrics such as rows scanned, bytes read from Amazon S3, and cache hits.
To see how direct querying works, I connected to my Aurora PostgreSQL database using psql and created the extension:
CREATE EXTENSION aurora_analytics;
For my walkthrough, I set up a simple financial scenario. I have a recent_transactions table in Aurora with the last 7 days of customer transactions, and a Parquet file in Amazon S3 containing 5 years of historical transaction data. To make Aurora aware of the historical data, I created a foreign table pointing at the Parquet file in S3:
CREATE FOREIGN TABLE transaction_history ()
SERVER aurora_analytics_server
OPTIONS (
    location 's3://<my-bucket>/finance/transaction_history.parquet',
    format 'parquet'
);
Notice the empty parentheses in the CREATE FOREIGN TABLE statement. Aurora automatically reads the schema from the Parquet file metadata, so you do not need to define columns manually. For workloads with many tables, you can skip creating them one at a time: a single IMPORT FOREIGN SCHEMA statement bulk-creates foreign tables for every Iceberg or Parquet table in an AWS Glue Data Catalog database, inferring schemas automatically.
With both tables in place, I ran a single query that combines the recent operational data in Aurora with the historical data in S3:
SELECT merchant, category, amount, transaction_date, 'recent' AS source
FROM recent_transactions
WHERE customer_id = 'C-1001'
UNION ALL
SELECT merchant, category, amount, transaction_date, 'historical' AS source
FROM transaction_history
WHERE customer_id = 'C-1001'
  AND transaction_date >= CURRENT_DATE - INTERVAL '5 years'
ORDER BY transaction_date DESC
LIMIT 15;
The result shows both recent and historical transactions in a single result set. The 7 most recent rows come from Aurora, and the rest come directly from the Parquet file in S3. DuckDB handles the analytical scan of the Parquet data under the hood, while Aurora handles the operational data. That single query would have previously required a pipeline to move the historical data into the database first.
If a query pattern needs single-digit-millisecond latency, you can materialize data from the data lake into a native Aurora PostgreSQL table using familiar commands such as CREATE TABLE AS SELECT, INSERT INTO ... SELECT, or MERGE INTO. The materialized table lives in Aurora and is queried like any other PostgreSQL table, giving you a low-latency path for hot data without operating a separate ingestion pipeline. The read queries can run on any Aurora PostgreSQL instance in your cluster, whether the writer or a read replica, so you can offload analytical scans from your operational workload. The materialization commands write data into Aurora, so they run on the writer instance.
Get started today
Direct querying of Apache Iceberg and Parquet data from Amazon Aurora PostgreSQL is available today in all commercial AWS Regions and AWS GovCloud (US) Regions, at no additional charge. You pay only for the incremental Aurora compute the queries consume and Amazon S3 request costs for reading data lake files.
Today, we’re excited to introduce the newest members of the AWS Heroes program. AWS Heroes are a vibrant, worldwide group of AWS experts who go above and beyond to share knowledge, mentor others, and build thriving communities. These individuals make a real difference in helping developers and organizations succeed with AWS.
This month, we welcome three exceptional community leaders from across the globe, each bringing unique expertise and a deep commitment to empowering builders everywhere.
Avinash Shashikant Dalvi – Bengaluru, India
Serverless Hero Avinash Shashikant Dalvi is a tech architect and co-organizer of AWS User Group Bengaluru who is focused on serverless, containers, and production-ready applications on AWS. He has delivered over 40 community talks, publishes the AWS for Product Builders newsletter, and creates technical content covering Amazon ECS, AWS Fargate, AWS Lambda, and AWS Amplify.
Joanne Skiles – Orlando, USA
Serverless Hero Joanne Skiles is an engineering leader and educator with over 16 years of experience building full-stack systems, including serverless architecture and AI systems on AWS. She organizes the Orlando AWS User Group and teaches cloud and AI concepts through her YouTube channel, conference talks, and her podcasts Chaotic Commits and Her Career Unplugged. Joanne is also a professor in the Computer Science department at Rollins College, where she runs the Transparent Systems lab.
Xiaofei Li – Shanghai, China
Community Hero Xiaofei Li is an AWS Golden Jacket holder and is an active community leader in the Greater China Region, leading the Kiro, Amazon Quick, and Tokyo Chinese AWS communities. He founded the Kiro Chinese User Community (5,000+ members) and initiated the Chinese localization of AWS Builder Cards across 15 cities and 3,000+ participants. Xiaofei also mentors underserved students and supports Women in Tech initiatives.
Learn More
Visit the AWS Heroes webpage if you’d like to learn more about the AWS Heroes program, or to connect with a Hero near you. To learn more about how to get involved with the AWS community, visit our AWS Builder Center.
Deploying Spark applications from a local development environment to a remote Amazon EKS cluster often means dealing with environment differences, dependency conflicts, and performance gaps at scale. Spark Connect removes this friction. It separates your application client from the Spark server, so you develop and debug locally while Spark Connect routes your operations to a scalable Spark cluster running on Amazon EKS.
This client-server architecture supports a range of use cases, including interactive development from notebooks and IDEs, embedded Spark in web services, and continuous integration and continuous delivery (CI/CD) data-quality tests. All of these run on your existing EKS infrastructure. Each Spark Connect session uses its own AWS Identity and Access Management (IAM) execution role, custom tags, and cost tracking. For more information, see the Amazon EMR on EKS documentation.
Here are two demonstrations of using Spark Connect in Amazon SageMaker Unified Studio Notebooks and in a VS Code local IDE:
Amazon SageMaker Unified Studio Notebooks demo:
Demo 1: Spark Connect running in an Amazon SageMaker Unified Studio notebook
Local IDE demo:
Demo 2: Spark Connect running in a local VS Code IDE session
For a runnable end-to-end example in an IDE, try the Spark Connect sample notebook in the aws-emr-utilities repository. It includes a client wrapper solution, built by AWS architects, for simplified connectivity:
Demo 3: Spark Connect client wrapper connecting to Amazon EMR on EKS from a local IDE
How Spark Connect works on Amazon EMR on EKS
Spark Connect uses a client-server architecture that separates application code from the Spark engine:
Client – A lightweight PySpark library running in your environment (such as an IDE or notebook). It doesn’t need Spark installed, direct access to data, or resources sized for the workload.
Connection (EMR managed endpoint) – The client sends Spark operations over a secure gRPC/TLS channel to the Spark Connect server.
Server – Runs Spark pods in your Amazon EMR on EKS namespace, starting from a minimum of two executors (adjustable) with autoscaling. The server performs Spark operations using the EKS compute resources and accesses data stores, such as an Amazon Simple Storage Service (Amazon S3) bucket, through job execution roles.
Results – The server streams query results back to the client through gRPC as Apache Arrow-encoded row batches.
On endpoint creation, Amazon EMR on EKS launches the Spark Connect server as pods on EKS and returns an Elastic Load Balancing (ELB)-backed endpoint and a short-lived token. You don’t need to provision any server or networking manually. Because the Spark Connect server runs on the EKS cluster you already operate, it inherits the node types, container images, and Spark configurations. What you see while developing Spark applications on the client side is what runs in the EKS environment at scale.
To provide a secure, simplified experience, Amazon EMR on EKS provisions two additional components on first use of Spark Connect on the EKS cluster:
Figure 2: Shared Envoy router and Secret Agent service on the EKS cluster
Managed authentication-proxy router – a shared Envoy router with three replicas by default (adjustable), fronted by a Network Load Balancer (NLB). It routes client traffic to the correct server pods, terminates TLS, and validates the session token. One router serves Spark Connect endpoints on the EKS cluster.
Secret Agent service – a lightweight, long-running pod that manages the short-lived credentials for session authentication. One service per EMR security configuration.
These components are long-running and shared across endpoints. Amazon EMR on EKS creates them automatically with the first endpoint on the cluster. Because the router is cluster-scoped and Secret Agent is namespace-scoped, deleting a managed endpoint doesn’t remove them. They keep running so that new endpoints can start within a minute. The router’s replica count is tunable. Scale down for non-production environments to reduce cost or scale up for higher throughput.
To fully remove these components:
Terminate all active managed endpoints and their virtual cluster that reference the Secret Agent’s security configuration, then delete the security configuration.
Once the last session-enabled virtual cluster is deleted, the authentication-proxy router and its underly resources, including the NLB and VPC endpoint, are removed automatically.
Alternatively, delete the EKS cluster to remove all in-cluster components at once.
Why use Spark Connect on Amazon EMR on EKS
With Amazon EMR on EKS, teams can run Spark alongside other applications on shared Kubernetes clusters with existing infrastructure, operational tooling, and system expertise. Spark Connect extends that value to interactive, embedded, and self-service Spark workloads. Your client stays lightweight while Spark code runs in governed, scalable server pods on EKS.
Interactive development on shared Kubernetes clusters
Data engineers and scientists iterate on Spark code cell-by-cell in notebooks or local IDEs. The Spark engine runs remotely on EKS, so validation runs on the same engine as your batch workloads. After validation on the Spark Connect client, the same Spark code deploys as a batch StartJobRun with no changes.
Spark Connect sessions run as pods on your existing cluster. They reuse your EKS RBAC, network policies, node autoscaling, and observability stack (Prometheus, Grafana, Amazon CloudWatch Container Insights). There are no separate compute and monitoring layers to operate.
Embedded Spark in applications and services
The Spark Connect client is a compact PySpark library. Teams can embed Spark operations directly into Python applications such as web services, dashboards, automation scripts, or backend APIs. The heavy processing runs on EKS while the application stays lightweight.
Teams can also expose Spark Connect as a self-service capability on their internal application. Business users submit Spark SQL scripts from a web UI. The compute runs on Spark Connect server on EKS, so the team manages capacity, security, and upgrades centrally.
Multi-tenant data exploration with governance
Each Spark Connect session uses the data user’s IAM permissions that you configure, limiting their access to authorized AWS services, data lake tables, and S3 paths. Every session carries tags with user, project, endpoint and virtual cluster IDs, feeding directly into billing and compliance reports. Meanwhile, data producers maintain guardrails on source data without blocking self-service exploration.
To manage resource consumption across teams, Amazon EMR on EKS virtual clusters provide namespace-level isolation. Each tenant binds their Spark Connect endpoints to a virtual cluster (a namespace) with independent IAM roles. Using resource quotas and limit ranges on EKS, you can protect each virtual cluster by controlling the compute resources that Spark Connect sessions can consume. Importantly, activating EKS split-cost allocation tags helps with chargeback reporting in a multi-tenant environment.
Reusable container images and scalable deployment
Teams often maintain custom container images with proprietary libraries, including internal feature stores, compliance toolkits, UDFs, or machine learning (ML) frameworks. With Spark Connect on Amazon EMR on EKS, teams reuse those same images as the Spark runtime for interactive sessions. No separate dependency lists needed. The same image works for both batch jobs and Spark Connect sessions.
Beyond the image itself, you can control Spark pod scheduling in Amazon EMR on EKS through pod templates and managed endpoint APIs, scaling across your environment. For example, you can:
Pin server pods to specific node types through pod templates. For example, Spot for cost savings.
Apply Spark Dynamic Resource allocation (DRA) to right-size each interactive session.
Use GPU node pools for accelerated Spark RAPIDS or ML.
Multi-cluster, multi-Region, and hybrid architectures
Enterprises running EKS clusters across multiple AWS accounts, AWS Regions, or hybrid environments with on-premises Kubernetes can use Spark Connect to query data wherever it’s processed. The lightweight client only needs to reach the Spark Connect endpoint, not the underlying S3 buckets or AWS Glue data catalogs. This means no VPC peering or direct network paths to every data store.
The client-server split is the core architectural advantage of Spark Connect on Amazon EMR on EKS. A developer on a laptop behind a VPN, a CI/CD deployment pipeline in a centralized service account, or an Airflow DAG orchestrating across Regions can all connect to a remote Spark server on EKS. This works regardless of where the client itself runs. This decoupling simplifies cross-Region or cross-account analytics without duplicating data or requiring direct access to each data store.
Getting started
To create a Spark Connect endpoint on Amazon EMR on EKS, complete the following steps:
Create EMR namespaces on EKS.
Create an EMR security configuration.
Create a virtual cluster with the security configuration.
Create a Spark Connect managed endpoint.
Obtain a session token.
Connect from your application.
Prerequisites
To proceed with this post, make sure you have the following:
Security note: Communication between your environment and the Spark Connect server is encrypted using TLS. The authentication token is time-limited (15 minutes by default). For long-running sessions, refresh the token periodically by calling get-managed-endpoint-session-credentials again. Consider using AWS Secrets Manager to store and retrieve tokens programmatically.
Step 6: Connect from your application
Use the returned endpoint URL and token to connect from a PySpark-compatible environment. The following Python code shows how to establish a Spark Connect session:
import os
from pyspark.sql import SparkSession
session_endpoint = os.environ["EP_URL"]
auth_token = os.environ["TOKEN"]
spark_conn_url = (f"{session_endpoint};use_ssl=true;x-aws-proxy-auth={auth_token}")
spark = SparkSession.builder
.remote(spark_conn_url)
.getOrCreate()
# verify the connection
print(f"Connected remotely! Spark version: {spark.version}")
# query data through the AWS Glue Data Catalog
df = spark.sql("SELECT * FROM my_catalog.my_database.my_table LIMIT 10")
df.show()
After you’re connected, you can:
Debug interactively – Set breakpoints, inspect DataFrames, and step through Spark code in your IDE or notebook while the operations run remotely on EKS.
Combine local and remote processing – Pull query results back to the client as a pandas or PyArrow DataFrame for local analysis, visualization, or ML (scikit-learn, notebook widgets), then push further Spark operations back to the server in the same session. Heavy processing stays on Amazon EMR on EKS. Only the results you request cross the wire.
Reconnect without losing state – A managed endpoint runs independently of single clients for a configurable idle timeout (default: 60 minutes). Your Spark session, cached data, and temporary views are preserved on the server between connections. When a session token expires (default: 15 minutes, configurable up to 12 hours), request a new token and reconnect to the same endpoint to resume where you left off.
Reuse across workload types – The same client connection pattern works everywhere Python runs: notebooks, IDEs, batch scripts, Airflow operators, or web services. One endpoint, one connection pattern, many workload types.
Validation
After you create the endpoint, verify that the Spark Connect server is running and reachable through Amazon EMR on EKS API and standard Kubernetes tooling:
# get endpoint status
aws emr-containers describe-managed-endpoint --virtual-cluster-id $VC_ID --id $EP_ID
# inspect the server pods (driver + executors) in your namespace
kubectl get pods -n $USER_NAMESPACE -l "emr-containers.amazonaws.com/managed-endpoint-id=$EP_ID"
# View driver logs
kubectl logs -n $USER_NAMESPACE <driver-pod-name> -c spark-kubernetes-driver
Figure 4: Endpoint status and the running driver and executor pods
# to view the live Spark UI, port-forward your driver pod:
DRIVER_POD=$(kubectl get pods -n $USER_NAMESPACE \
-l "emr-containers.amazonaws.com/managed-endpoint-id=$EP_ID,emr-containers.amazonaws.com/component=driver" \
-o name)
kubectl port-forward -n $USER_NAMESPACE "$DRIVER_POD" 4040:4040
# Open http://localhost:4040 in your browser
Figure 5: Live Spark UI for the Spark Connect session
Spark Connect endpoints run as pods on your EKS cluster. The existing Kubernetes observability stack, such as CloudWatch Container Insights, Prometheus, and Grafana, captures Spark Connect endpoint metrics alongside other cluster workloads.
Clean up resources
Terminate your session when you’re done to avoid ongoing costs:
# (OPTIONAL) Endpoints are auto-deleted after the idle timeout (default: 60 minutes).
aws emr-containers delete-managed-endpoint \
--virtual-cluster-id $VC_ID \
--id $EP_ID
# Delete the virtual cluster only when no active endpoints remain
aws emr-containers delete-virtual-cluster --id $VC_ID
# Delete Security Configuration
aws emr-containers delete-security-configuration --id $SEC_CONFIG_ID
# remove the remaining EKS namespaces
kubectl delete namespace $USER_NAMESPACE $SYS_NAMESPACE spark-connect-router
Deleting or timing out a managed endpoint automatically removes its corresponding driver and executor pods. The Envoy router and Secret Agent service are shared across endpoints on the EKS cluster and remain running when individual endpoints are terminated. To fully remove these shared components, delete the virtual cluster to remove its corresponding Secret Agent service. Before doing so, ensure that no managed endpoints in the virtual cluster are active. Terminating the last session-enabled virtual cluster automatically removes the Envoy router from the EKS cluster.
Availability and pricing
Spark Connect on Amazon EMR on EKS is available with EMR release 7.14 (Apache Spark 3.5) and emr-spark-8.1 (Apache Spark 4.1), in all AWS Regions where Amazon EMR on EKS is available, except the AWS GovCloud (US) Regions and the China Regions. The Amazon SageMaker Unified Studio experience is available in supported Regions.
There is no additional charge for Spark Connect managed endpoints beyond the standard Amazon EMR on EKS pricing. You pay for underlying Amazon EKS resources such as EC2 and ELB. For timed-out or terminated managed endpoints, EMR automatically removes their Spark pods from the EKS cluster.
Recommendations for cost efficiency:
Use Karpenter (or Cluster Autoscaler) to right-size cluster capacity to session workload demand. This provisions nodes when endpoints need them and removes them when idle, which keeps cost aligned to actual usage.
Schedule interactive session pods on On-Demand instances for persistent compute.
Keep a single, shared Envoy router and NLB serving all Spark Connect endpoints (the default) on the cluster. Right-size the router replica count (three by default) for your availability requirements.
In this post, we showed how, with Spark Connect on Amazon EMR on EKS, you can build, test, and debug Spark applications from the tools you already use: IDEs, notebooks, Amazon SageMaker Unified Studio or Airflow. Your workloads run at scale on your existing Kubernetes clusters, with no application code changes.
For teams already running Amazon EMR on EKS, Spark Connect extends your virtual clusters to interactive and embedded workloads. The same virtual cluster that runs your batch StartJobRun jobs now also serves Spark Connect sessions. Each session runs as pods on your EKS cluster, inheriting your node groups, container images, and Spark configurations. Each session also carries its own IAM execution role and cost tags. This extends the security, multi-tenancy, and observability of your Amazon EMR on EKS investment to a broader set of users and use cases.
Event-driven applications on Amazon EventBridge usually start small and then spread. One team creates a Custom event bus, adds a few rules, and ships. Another team needs some of those events, so a rule forwards them to a bus in a second account. A third team needs a subset of what the second team receives, so another rule forwards again. A year later the organization runs dozens of Custom event buses joined by forwarding rules, and that topology has become a thing to operate in its own right.
That shape has a price, and the smallest part of it is the bill. Every forwarding hop is a separate ingestion, so cost tracks the topology rather than the number of consumers that needed the event. The harder problem is that nobody can see the whole picture. Governance spreads across the accounts it was meant to cover. Answering who publishes to a bus, who consumes a given event type, or what breaks when a team stops publishing means visiting each account and reading its rule configuration. Tracing one event is harder still: its path crosses several buses in several accounts, each with its own metrics and logs, and no single view follows it from publication to the consumer that never received it.
Application teams also wait. Publishing to a bus in another account, or consuming from one, needs a resource policy, a role, and a forwarding rule owned by a central team. The team that wants to build opens a ticket, and the platform team becomes a queue. Both the missing visibility and the waiting grow with every team onboarded.
Amazon EventBridge recently relaunched the Custom event bus, which tackles these challenges directly. A platform team creates one bus, shares it across the organization, and keeps control of who can publish and who can subscribe. Every consumer of those events is listed on the one bus rather than inferred from configuration spread across accounts. Application teams create their own Subscribers in their own accounts. The bus stores events for a retention period you choose, preserves order within a key the publisher sets, accepts Avro and Protocol Buffers (Protobuf) alongside JSON (including CloudEvents), and delivers to targets without a function in the path to translate a call. It runs alongside the Custom event bus – classic, so adoption is incremental.
In this post, you see how a platform team stands up a shared bus and governs access to it, how application teams onboard themselves with a single Subscriber resource, and how retention, ordering, open formats, transformation, and direct target integrations change what one bus can carry.
One bus, shared with the organization
The platform team’s job on a shared bus is narrower than it was on a fleet of them. It owns the bus and sets the boundaries: which principals can publish and what their events can declare, which principals can subscribe, and, where it matters, what those principals are allowed to filter on. Application teams then manage their own configuration within those boundaries, such as filters, targets, delivery roles, retry policies, and failure destinations, none of which the platform team needs to write or review. That division is the point of the design. The platform team keeps governance of the bus and stops owning everyone else’s configuration, which is what takes it out of the provisioning path without giving up control of who is on the bus.
Creating the bus is a single call in a platform account.
Retention is the one setting worth deciding deliberately here rather than revisiting after an incident. It runs from 1 to 365 days and can be modified later, but a change only applies going forward. Raising it widens the window for events published from that point on, and does not make older events readable again. Seven days covers a working week of history, which is usually enough to onboard a consumer or reprocess after a bug without paying to store a year of events nobody will read.
Sharing the bus is the second decision. AWS Resource Access Manager is the route to reach for first: it associates automatically for accounts in the same organization and reaches accounts outside it by invitation the consumer accepts. A resource policy written on the bus directly is the alternative, and can also name accounts inside or outside the organization.
Access is granted per principal, and publishing and subscribing are separate permissions. A team that produces order events gains no ability to read payment events from the same bus. One grant is not enough for a cross-account caller, as usual on AWS: the role that publishes or subscribes also needs its own IAM policy allowing those actions. The platform team decides which accounts can reach the bus, and each consuming team decides which of its own principals can use that access.
Taken together, those decisions produce the architecture in the following diagram. One bus lives in a platform account, and application teams publish to it and subscribe from their own accounts. An AWS Lambda function in Team A’s account calls PutRawEvents to publish events onto the Amazon EventBridge bus in the platform account. Team B and Team C each attach their own Subscriber: Team B’s delivers to a Lambda function, Team C’s to an Amazon DynamoDB table.
Figure 1: Multi-account sharing
Cost follows team boundaries because charges separate ingestion from delivery. The account that publishes an event pays to put it on the bus, and the account that owns a Subscriber pays for what that Subscriber consumes. Each team’s usage appears on its own bill, which is what makes a shared bus something a platform team can charge back rather than a shared cost center nobody can decompose. Removing the forwarding hops also removes the duplicated ingestion and delivery those hops created: the same event reaching the same three consumers is ingested once instead of three times.
Publishing in the format teams already use
Not every producer speaks JSON. Teams that standardize event exchange across an organization often register schemas and publish compact binary payloads, because the schema is the contract between teams that deploy on their own timetables. Accepting the formats those producers already emit is simpler than changing each one to convert to JSON first.
With the new Custom event bus, application teams can publish events in Avro, Protobuf, and CloudEvents (JSON) formats. For the binary formats, a schema registry named on the request is used to deserialize the events.
There are two publish APIs, and the payload decides which one to call. PutEvents takes structured JSON with the familiar Detail, Source, and DetailType fields. PutRawEvents takes a binary payload plus metadata you define, and is the one to use for Avro, Protobuf, CloudEvents, or bytes the bus should not interpret.
The schema registry can be either the AWS Glue Schema Registry or the Confluent Cloud Schema Registry.
Because the bus decodes the event before filters and transformations run, a consumer subscribing to Avro events written by another team needs no schema, no decoder, and no access to the registry. It writes the same filter it would write against JSON. Producers and consumers stay decoupled, and no deserialization code has to be repeated in each consuming team.
Publishers get one more setting on the same request: deduplication. A retry that already succeeded would otherwise leave a duplicate for every consumer to handle. It works one of two ways: the bus hashes the content of each event, or it uses a deduplication ID you supply. Content-based hashing suits producers with no natural key, since two identical events hash the same. A deduplication ID fits when you already have one, such as an order ID combined with a state transition. It keeps matching even when parts of the payload differ in ways that should not count as a new event.
Self-service onboarding for application teams
The new Custom event bus introduces a new resource called a Subscriber. Application teams create and configure their own Subscribers in their own accounts, provided they have been granted subscribe access to the bus. A Subscriber is the one place a consumer’s behavior is defined: which events it receives, where they are delivered, how delivery is retried, and where events go when delivery does not succeed. Reviewing or changing a consumer is one thing to read and one thing to update.
A filter’s scope decides which part of the event the pattern is matched against. DATA matches the payload, METADATA matches the key-value pairs the publisher attached to the event, and SYSTEM_METADATA matches the event’s system fields: the content type and ordering key a publisher declares, plus the fields Amazon EventBridge adds itself. Because Avro and Protobuf payloads are decoded as they are published, a DATA filter reads their fields directly, the same as it would for JSON.
The retry policy says how the bus should behave when a target is failing. MaxRetryAttempts sets how many times a delivery is retried, and MaxEventAgeInSeconds sets how long an event stays eligible for retry, measured from when it was published. Retries stop as soon as either limit is reached, so both bound the same delivery.
When deliveries do fail, the reason shows up in the Subscriber’s own logs, which application teams can turn on themselves. They record the error from each delivery attempt alongside the exact input sent to the target, which makes a problem quick to place. Seeing what the target actually received separates a transformation that produced the wrong shape from a target that rejected a correct one.
Figure 2: Creating a Subscriber on console
History for consumers that did not exist yet
A Subscriber sometimes needs events that were published before it existed. For example, a new analytics service needs hydrating with recent history, or a target processed a window of events incorrectly and needs that window replayed. Because the bus retains events for the period configured on it, a Subscriber can be created with a starting position in the past, so it reads history, catches up, and continues with live traffic:
A starting position is either LATEST or POINT_IN_TIME. Choosing POINT_IN_TIME then needs a point-in-time configuration: a PointType of TIMESTAMP with a starting point, or HORIZON to begin at the earliest event still retained. An optional end point stops the read at a chosen time, which is what you want when reprocessing a known-bad window rather than catching up to live traffic.
Two things to keep in mind. The starting position is fixed when the Subscriber is created, so reading a different window means a new Subscriber. Treat the starting position as part of a Subscriber’s identity rather than a dial to turn later. And retention cannot reach back beyond the retention window, so the read starts at the earliest retained event however far back the timestamp asks for.
Order, where order matters
In event-driven architectures, where components are built to work asynchronously, the order events arrive in usually does not matter. There are still use cases where a consumer relies on ordered delivery, and the new Custom event bus offers it as an option on individual Subscribers.
Ordering is scoped by a key the publisher sets. A publisher includes an event group ID (a customer ID, an order ID, a driver ID), and a Subscriber created with FIFO delivery type receives the events for each group in the order they were published. A FIFO Subscriber reading events published without a group ID has nothing to sequence by, so the two sides work together. Creating one takes the same call as an unordered Subscriber, with the delivery type set to FIFO:
Ordering is per group, so throughput scales with the number of groups. If an event cannot be delivered, it holds up the rest of its own group while other groups keep moving. Choosing the key therefore matters: one that maps to a business entity, such as an order or a customer, gives sequencing where it is needed and independence everywhere else. A key so broad that most events share it puts them all in a single sequence, and a key so specific that every event has its own leaves nothing to order.
Because ordering is set on each Subscriber, consumers of the same events do not need to agree on it. An inventory service can receive a group’s events in sequence while an analytics service subscribing to those same events takes them as they arrive.
Reshaping events, and delivering directly to a target
A consumer’s business logic expects events in a particular shape, and the events on the bus are not always in that shape. Where the two get reconciled is an ownership decision: inside the consumer, where it becomes part of that team’s code, or on the Subscriber, ahead of it.
The first case is reformatting. A downstream system, often owned by another domain or outside the organization entirely, expects a different structure from the one the publisher emits. A JSONata transformer on the Subscriber produces that structure before delivery, so the consumer receives what it already expects. The business logic stays where it belongs, and when the published shape changes upstream, or another event type needs deriving into the same input, it is the transformer that changes rather than the consumer:
The transformer type determines the shape of what gets delivered. RAW delivers the event payload as is and is the default, so a Subscriber with no transformer configuration receives only the payload. WITH_METADATA adds the event envelope alongside it, and JSONATA reshapes it with an expression wrapped in {% %}.
The transformation reshapes events only for the Subscriber that owns it and does not affect what other Subscribers of the same bus receive. That also makes it a data minimization control: a partner can receive only the fields it needs rather than a whole internal event. Defining it at the Subscriber means it holds for every event without anyone remembering to strip fields.
Note that a universal target shapes its input through that parameter rather than through the preceding transformer, and setting a transformer on one is rejected when the Subscriber is created. The two mechanisms do the same kind of work on different targets.
That removes the proxy processing that existed only to make the call. The delivery role still needs the action the target requires and getting that wrong is the most common cause of a Subscriber that looks healthy and delivers nothing.
Conclusion
Running an event-driven application across many accounts no longer means running many event buses and the forwarding between them. A platform team creates one new Custom event bus, shares it across the organization through AWS Resource Access Manager or a resource policy on the bus, and keeps one place to decide who publishes and who consumes. Application teams create and own their Subscribers without waiting for provisioning. Ingestion and delivery are charged separately, so each team’s usage appears on its own bill, and the duplicated ingestion that forwarding hops created disappears with the hops.
The capabilities that used to send individual teams elsewhere now sit on the same bus. Ordering is per Subscriber and scoped by a publisher-supplied key, so one team’s sequencing requirement no longer fragments an architecture. Retention makes it possible to onboard a consumer that needs history it was never subscribed to. Avro and Protobuf are decoded by the bus, so producers keep their binary contracts. Transformation and universal targets keep business logic where it belongs, removing the proxy steps that existed only to reshape an event or make an API call.
Because the new Custom event bus runs alongside the Custom event bus – classic, adoption is incremental. Point one new consumer at a shared bus or forward a slice of an existing bus into it and move the rest as teams are ready.
Next steps. Create a bus, add a Subscriber, and publish an event, starting from the Amazon EventBridge documentation for the resource model and the AWS Command Line Interface (AWS CLI) reference. If you already run Custom event buses, the migration guidance covers routing existing events into a new Custom event bus without changing producers. From there, look at the Subscriber logging and metrics options for tracing an event from publication to delivery, and at AWS Resource Access Manager for how sharing and permissions work across an organization. If you have questions or feedback about the new Custom event bus, leave a comment on this post. We’d like to hear how you’re using it.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.