Tag Archives: Analytics

DataJunction as Netflix’s answer to the missing piece of the modern data stack

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/datajunction-as-netflixs-answer-to-the-missing-piece-of-the-modern-data-stack-92af926b40a5

by Olek Gorajek, Samuel Redai, Yian Shang

Intro

Our Netflix journey from data to dashboards, particularly within the space of the experimentation platform, always presented a unique set of challenges. This blog post aims to illuminate these hurdles and explain how an innovative open-source metric platform became instrumental in overcoming some of them. We’ll showcase the critical role that DataJunction played in streamlining our data workflows and enhancing our ability to derive meaningful insights from our vast datasets.

Metrics are the foundation of data-driven decision-making, but at many organizations, they are scattered, inconsistently defined, and difficult to discover or trust. At Netflix, this challenge first became apparent in our experimentation platform, where reliable metrics are essential for interpreting test results. But the complexity of the original tooling made it very difficult to understand and introspect these metrics both in terms of their definitions as well as their values.

Initial Problem

Scattered metric definitions, redundant datasets, and pipelines are often a natural effect of a fast-moving company with a large and powerful analytical workforce. This is a common problem in big data-driven firms, and it is not easy to solve across multiple departments, which are often governed by somewhat different rules and regulations. An easy-to-use, well-governed, and centralized semantic layer can help with these issues. Our initial problem was most evident in our Experimentation Platform team, where the previous system required:

  • extensive business knowledge
  • familiarity with experimentation conventions
  • and complex engineering practices

This led to metric authoring processes that would take weeks, which was a prohibitive requirement for Data Scientists and Analytics Engineers who wanted to onboard new metrics to the Experimentation Platform.

Enter DataJunction

To address this problem and to set ourselves on the path to a successful semantic layer solution in the future, we looked at several candidates. Among other solutions we evaluated Mando (an internal framework), Minerva (an open source semantic layer from AirBnB), and DataJunction (another open source solution, “DJ” for short). All of them had some strength, but DJ offered one thing that the others did not at the time: a solid SQL parsing and SQL generation engine. At the time of the POC, DJ was also the only open-source solution that stored all its definitions in a connected graph, similar to how relational databases store metadata on their views and queries. Easy “SQL wrangling” with rich metadata was the main feature that convinced us to try it for our immediate use case.

DataJunction originated from a similar internal Facebook project created (around 2015) by the data science and infrastructure (DSI) team, mainly as an answer to the need for metrics portability. During several iterations of the Deltoid project — which was the main experimentation platform at Facebook at the time — users were required to rebuild and repopulate their metrics when they wanted to move to the next version of Deltoid. But after implementing DJ and abstracting all metric definitions the team offered seamless migrations by separating the concerns between the metrics and the stats computation platform. That project was subsequently renamed to MDF (Metrics and Dimensions Factory) and promoted as a generic semantic layer used widely by various departments. In 2021, one of the Facebook engineers (Beto Dealmeida), started the DJ Github project and built out some basic functionality. Then together with some folks at Netflix expanded the scope further, and soon after that the project was introduced at Netflix. Following that introduction, three Netflix engineers (authors of this blog) together with a couple of external contributors, most notably Nick Ouellet, have been building out the remaining features of the platform.

Architecture Decisions

A critical design constraint for building DJ at Netflix was resource scarcity. We refused to compromise on product quality, choosing instead to limit the feature set. Although DJ was clearly capable of addressing many simultaneous problems across diverse use cases, our lack of adequate resources and official support meant we developed it as a side project for over two years. Our hope was that demonstrating its value would eventually secure management attention.

API First, UI and Other Interfaces Later

A metrics platform doesn’t need a flashy front-end to deliver value — its core is the semantic layer, which stores a consistent set of dimensions and metrics and serves this information through a rich API service. You can see below how we structured the main components of DataJunction in the Netflix implementation. Our DJ services (in the middle) interact with the underlying data (on the left) and supply our access layer with the business definitions in the form of SQL w/ metadata or directly with data depending on the client request.

Consistent Graph First, Other Features Later

A complete semantic layer system can seem like an octopus, with its tentacles reaching out into many functional areas and can expand from a basic semantic metadata stored for some datasets to full dashboard functionality. Let’s call out some of them:

  • semantic metadata authoring and management and monitoring
  • metric and dimension query / definition generation
  • metric and dimension data generation (requires a query engine)
  • data visualization and data tracking
  • performance optimization (aka caching or materialization)
  • integration layer with other tools and
  • any / all the above functionality served as: UI, API, client libraries, MCP servers and more.

Of course it is extremely hard to provide the best in class functionality across all these layers, so with our small “unofficial” team we decided to focus on the most important piece: solid semantic layer engine (and API) with the ability to parse SQL as the input to the graph and generate SQL as the serving layer. That is the core of the system and everything else can be added later with less effort and w/o the need to rebuild the core.

Cube as The Perfect Consumption Protocol

Analytical multi-dimensional cubes have been a fundamental concept for decades, with their representation integrated across various data processing and analysis platforms. While definitions and features may vary between tools, they all serve the common purpose of encapsulating, or abstracting, a subset of semantic objects.

In DataJunction, we adopted cubes as first-class features for two main reasons: their familiarity to users and their suitability as a serving interface. They efficiently deliver both the semantic definitions (of metrics and dimensions) and fast data access. See an example of data “flow” graph (dotted lines) and dimensional relationships graph (solid lines) below.

We simplified the creation of basic cubes, allowing them to easily aggregate arbitrary collections of shared metrics and dimensions. Furthermore, accessing, managing, and visualizing these cubes is straightforward for any client integrating with DJ. Custom integrations, such as for Netflix’s internal fast Druid data analysis tool (Data Explorer → see below), became trivial to build, and we also made it easy to materialize these cubes directly in our Druid clusters.

One of DJ’s most powerful client integrations is the ability to link any DJ-originating metric definition back to the DJ ecosystem. This creates a valuable feedback loop: troubleshooting and introspecting business dashboards becomes simple if they display DJ-defined metrics that include links back to the definition source. This link then makes inspecting and running ad-hoc analysis, by modifying existing metrics, a trivial process. This integration is not only possible with our inhouse tools, but also with other well known open-source products, like Superset.

Experimentation at Netflix

Metrics are the backbone of experimentation. They translate data into signals that tell us whether a change is meaningful, safe, and worth scaling. Without trustworthy metrics and dimensions, experiments risk becoming inconclusive or misleading, so a robust metrics layer becomes crucial for data-driven decisions.

At Netflix, the original metrics layer integrated into the experimentation platform was overly complicated. Creating new metrics not only required tribal knowledge of experimentation data artifacts, but also familiarity with complex engineering workflows. This unnecessary friction meant that onboarding a single new metric could take weeks, slowing adoption of new metrics and hindering experimentation.

This is where DataJunction comes in: it provides a central hub for defining metrics and dimensions that can easily be shared and explored via the semantic graph. It also provides flexible, user-friendly interfaces (including a UI, API, and various clients), making it easy for users to author and manage their metrics and other semantic models.

Conclusions

With experimentation domain well supported by DataJunction, we would like to take on next steps to unifying of the general analytics at Netflix and to make it easier for Netflix users to both:

  • find and use metric definitions across verticals (defined in DJ)
  • easily access, modify and experiment with new metrics across Netflix data stack

That will require building out strong integrations between DJ and other tools, but that has been underway and it is one of the most enjoyable parts of this project, where most of the feature exists and we are simply enabling existing systems to exchange information in a structured and reliable way. With a system like DataJunction our internal LLMs can deliver accountable information about the business metrics as well as explanation of how they are defined and used across Netflix.

Related resources:

  • 2023 : DataJunction at Netflix (slide deck)
  • 2025 : DataJunction talk at Data Engineering Open Forum 2025 (video)
  • 2025 : DataJunction: Unifying Experimentation and Analytics (blog)


DataJunction as Netflix’s answer to the missing piece of the modern data stack was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.
GrabMart data for faster disease outbreak detection

Post Syndicated from Grab Tech original https://engineering.grab.com/grabmart-data-for-faster-disease-outbreak-detection

Abstract

Retail purchases can supplement clinical surveillance because changes in demand for some over-the-counter (OTC) products may appear before confirmed case reports. This article describes an early-stage concept for analysing aggregated GrabMart transaction data to identify unusual changes in product demand. The concept is not a deployed system, and it would require validation by public health experts, privacy review, and regulatory approval before any implementation.

Introduction

Public health agencies use sources such as clinical case reports, laboratory results, and hospital records to monitor disease activity. Retail data may offer an additional signal when demand changes across groups of symptom-related products. It cannot establish a diagnosis or replace clinical evidence.

When using indirect signals, we should assess whether they remain relevant to the outcome we want to measure. This includes considering how changes in user behaviour could affect their interpretation. A retail-based signal can experience similar drift, selection bias, and false alarms. Any useful design must therefore combine statistical validation with careful privacy and governance controls.

Background

Syndromic surveillance tracks patterns that may indicate emerging illness before diagnoses are confirmed. Retail surveillance applies this idea to changes in demand for products associated with symptoms, such as fever remedies or cough medicines.

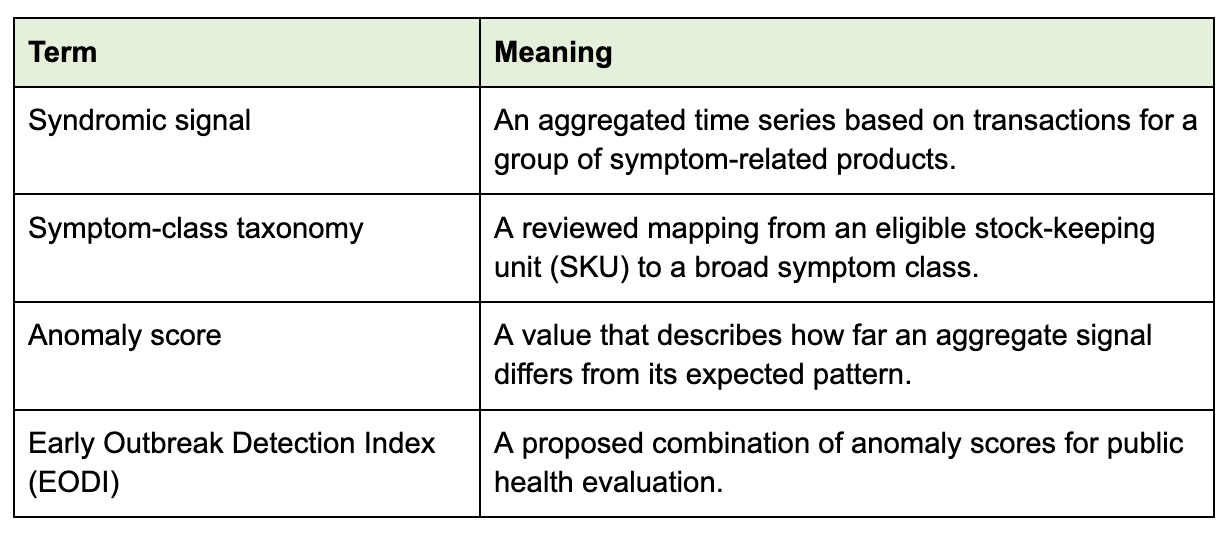
The proposed method groups eligible products into broad symptom classes and measures changes in aggregate demand over time. An anomaly score can indicate that observed demand differs from an expected seasonal pattern. The score is a statistical signal, not an estimate of how many people have a disease.

The design uses the following terms:


Proposed solution

The proposed pipeline would process only transactions that meet documented eligibility rules. It would map eligible SKUs to symptom classes, aggregate counts across approved time periods and geographic areas, and compare each series with an appropriate baseline. Public health experts would review the resulting Early Outbreak Detection Index alongside independent evidence.

The method deliberately excludes identity linkage and individual-level health inference. It also avoids using a single purchase to classify a customer, target an advertisement, adjust an insurance decision, or change access to a product.

Conceptual data flow

Eligible transactions
        |
        v
Reviewed SKU-to-symptom mapping
        |
        v
Aggregate by approved time period and geographic area
        |
        v
Compare with seasonal and historical baselines
        |
        v
Privacy and quality checks
        |
        v
Aggregate signal for authorised public health evaluation

Analysis and validation

Several statistical methods could model expected demand, including seasonal time-series models and spatial scan statistics. Model selection should follow retrospective evaluation against approved public health data. Evaluation should measure sensitivity, false-alert rate, calibration, geographic stability, and performance during seasonal changes.

The system would also need ongoing monitoring. Product catalogues change, purchasing behaviour shifts, promotions affect demand, and access to GrabMart varies across populations and locations. These factors can produce anomalies unrelated to disease activity.

Privacy and governance

Privacy protection starts with data minimisation. The analysis should use only eligible product categories, coarse geographic areas, and aggregate time windows approved for the stated public health purpose. It should not expose raw transactions or personally identifiable information (PII).

The release process could apply minimum-count thresholds and differential privacy (DP), subject to a documented privacy analysis. Privacy specialists would need to set and review any privacy budget. Access controls, retention limits, audit logs, and contractual restrictions would govern any approved data exchange.

An independent review should cover privacy law, health-related inference, fairness, scientific validity, and the risk of harm from false alerts. An authorised public health body, rather than an automated model, should decide whether and how to communicate a possible outbreak.

Potential applications

If research validates the signal and the required approvals are in place, aggregate trends could support:

  • public health research alongside established surveillance sources;
  • operational planning for broad categories of health supplies; and
  • evaluation of whether retail demand contributes useful evidence during an emerging event.

These applications should use aggregate trends only. The signal should not drive personalised medical advice, individual targeting, insurance decisions, or automatic changes to medicine search rankings.

Limitations

Retail demand is an indirect and incomplete measure of illness. Purchases may reflect promotions, weather, media coverage, household stocking, or changes in product availability. GrabMart customers are not representative of the full population, and the available product mix differs by market.

Mapping a product to a symptom class is also uncertain because many products have several uses. Aggregation and privacy controls reduce disclosure risk but can weaken statistical utility. These limitations require local validation and documented thresholds before anyone interprets the index.

Conclusion

Aggregated retail transactions may add a timely signal to public health research, but they cannot replace clinical surveillance. A responsible design must minimise data, prohibit individual health inference, test the model against independent evidence, and place public health experts in control of interpretation and communication.

This concept remains in the early planning phase. No production deployment, measured performance result, or public health integration is claimed.

Join us

Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors. Serving over 900 cities in eight Southeast Asian countries: Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam. Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. We operate supermarkets in Malaysia under Jaya Grocer and Everrise, which enables us to bring the convenience of on-demand grocery delivery to more consumers in the country. As part of our financial services offerings, we also provide digital banking services through GXS Bank in Singapore and GXBank in Malaysia. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line. We aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!

Smarter personalization: How property data helps us understand user price sensitivity

Post Syndicated from Grab Tech original https://engineering.grab.com/price-sensitivity-profiling-using-llm

Introduction

Existing systems estimate user price sensitivity primarily from spending behavior or demographic proxies. They do not systematically account for residential property values, which can indicate a user’s financial circumstances. This omission creates three limitations:

  1. Limited property insights: Existing profiles do not account for property values.
  2. One-dimensional profiles: Users with similar spending patterns but different living standards receive the same classification.
  3. Regional variation: Manual classification does not adapt well to differences between property markets.

This invention adds property data to user profiles to produce affluence segments that account for regional property markets. The invention remains unimplemented and is not deployed in any live market.

Background

Property values vary across buildings, neighborhoods, and regions. A useful classification method must account for these differences while processing property records in several formats. The same classification method could support other industries that use affluence segments.

Solution

A four-step method that combines public property data with clustering techniques to classify user affluence was created:

  1. Data collection and enrichment.
  2. Building-level property price estimation.
  3. Property tier classification.
  4. User mapping to affluence tiers.

The method combines external property data, large language model (LLM) enrichment, and cluster-based segmentation. The resulting profiles can inform personalized offers, targeted marketing, and operational planning.

Data gathering and processing

The system collects public property data from external sources. These records include transaction prices, building types, and related attributes in raw text formats. LLMs standardize the records and extract key attributes such as postcode, building address, transaction price, price per square meter, property size, and floor level. This stage produces a structured property-level dataset for analysis and modeling.

Building-level price estimation

Under the proposed method, transaction records for properties within the same building would be aggregated to calculate a weighted average sale price. The weighting would account for transaction recency and data volume, with the aim of reflecting recent market conditions.

When transaction data is limited, the method could apply rules based on comparable properties in the area. It could also evaluate LLM-assisted extraction of contextual signals from appropriately licensed external sources, such as real estate listings. Any LLM-derived signals would require validation against independent reference data before contributing to a property-value estimate.

The invention has not been implemented, deployed, or tested in a live market. Its model and version, validation methodology, error bounds, and operational safeguards remain subjects for future technical evaluation.

Property tier classification

A hierarchical clustering model groups buildings into affluence tiers based on their estimated resale values. The model accounts for regional differences and local market-value distributions across property types and locations. This stage assigns each building to an affluence tier.

User mapping to property tiers

The system maps would use appropriately aggregated geographic signals to associate users with broad property-market segments and assign a corresponding affluence classification.

Potential future applications

This invention presents a conceptual approach for exploring new ways to support personalization, advertising, and operational planning. It has not been implemented, deployed, or tested in a live market. Subject to technical validation and approval from Privacy, Legal, PR, and the relevant product owners, potential applications could include:

  • Personalization: Tailoring promotions, discounts, subscription plans, and recommendations for optional products and services.
  • Advertising: Supporting more relevant connections between advertising content, merchants, and broad audience segments, alongside tailored marketing campaigns.
  • Operational planning: Informing aggregated analysis used to plan and prioritize delivery and transport capacity.

Learnings and conclusion

This invention presents a conceptual approach that combines publicly available property data, LLM-assisted data structuring, building-level value estimation, hierarchical clustering, and contextual tier assignment. It demonstrates how regional property-market context could complement existing signals, while highlighting dependencies on data quality, model accuracy, geographic coverage, privacy, and fairness.

The approach shows potential applications in personalization, advertising, and operational planning, but these are illustrative, not demonstrated outcomes.

Join us

Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors. Serving over 900 cities in eight Southeast Asian countries: Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam. Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. We operate supermarkets in Malaysia under Jaya Grocer and Everrise, which enables us to bring the convenience of on-demand grocery delivery to more consumers in the country. As part of our financial services offerings, we also provide digital banking services through GXS Bank in Singapore and GXBank in Malaysia. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line. We aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!

Identify AI model overuse with User Insights

Post Syndicated from Ayush Kumar original https://blog.cloudflare.com/ai-model-overuse-user-insights/

When we launched User Insights last month, we wanted to help teams answer a basic question: What are people actually doing with AI? User Insights gives teams a clearer view of their AI usage, showing which users, applications, tasks, and models are driving traffic. It also highlights user and agent anomalies, helping teams identify unexpected or out-of-control spending and usage before they become larger problems.

Our latest update adds something our users have been asking for: context. 

Since launch, we’ve heard from users that model names and request counts only tell part of the story. They show where traffic is going, but reveal little about the work behind it: is that request a code review, a research task, or an agent making several calls to complete a job? The same token count can represent very different kinds of work, and you can’t evaluate with model choice without understanding the task.

User Insights now shows when a model may be more capable than a task requires, which of your users and agents are driving that usage, and how the task, model, cost, and conversation patterns relate. Teams can use these insights to investigate and make targeted changes within their organization. These capabilities are available for free to AI Gateway users.

Why AI usage is hard to understand

Consider a team that has routed its internal AI traffic through AI Gateway. After a few weeks, spending is increasing and some requests feel slower than expected, a common challenge as organizations adopt AI at scale.

There could be several explanations. Developers may be using AI for increasingly complex coding work. Agents may be making too many follow-up calls to complete a task. Or a small group of users or agents may be responsible for a disproportionate share of the organization’s usage.

Tokens and request counts alone cannot show which pattern is driving the increase. Teams need to understand what the traffic represents before deciding whether a model, workflow, or routing rule should change.

Helping teams find where AI models are overkill 

The model overkill view helps teams identify conversations where the selected model appears to be more capable than the task requires. For example, a team might discover that users or agents are sending simple formatting or summarization requests to a high-capability reasoning model.

That gives the organization a place to start. They can see which users, agents, or applications are associated with the pattern, then investigate the tasks behind it. A team might find that a model is being used because it is the default, because users are unsure which model to choose, or because an agent has been configured to use the same model for every step.

The overkill view is not a leaderboard and does not automatically recommend a replacement model. It helps teams ask better questions:

  • Is this model appropriate for the task?
  • Is the extra capability improving the result?
  • Would a faster or less expensive model produce an equivalent outcome?
  • Is the issue limited to one workflow, user, or agent?

From there, teams can compare cost, latency, token usage, and conversation turns before deciding what to change.

These insights support both the new Potential Savings view and the Auto Router, which is launching in public beta alongside this release. The Potential Savings view helps teams identify requests that may be handled by a faster or less expensive model without compromising output quality. The Auto Router applies these task and model-fit signals automatically, helping reduce costs without requiring a separate routing rule for every workload.

The Overkill view is a starting point for evaluating model fit. Teams can compare latency, input and output tokens, conversation turns, and total cost for the same type of task. A difficult coding or research task may need a capable reasoning model, while a short summary or simple classification task may not. The goal is not to move every request to the least expensive model, but to understand whether the selected model is appropriate for the work.

Understand what people are using AI for

Task analysis groups conversations by the kind of work they represent. Initial categories include coding, research, writing, summarization, and data analysis.

This provides context that a list of model names cannot. An engineering team might use AI mostly for coding and debugging, while another team might use it for research and summarization. A team may also discover that a surprising amount of traffic comes from simple tasks, even though those tasks are being sent to a high-capability model.

The answers will vary by team. The category data provides a way to investigate those differences using traffic already passing through AI Gateway. Teams can determine whether a model is being used for the work it is best suited to handle, or whether a default model is being applied too broadly.

Understand the full cost of a task

Some tasks are finished in one exchange. Others take a few rounds of questions, corrections, and follow-ups. Turns analysis shows how much back-and-forth different tasks require. A long conversation is not necessarily a bad thing, especially for complex work. But if a simple task keeps taking several turns, it may be worth looking at the prompt, the model, or the workflow.

The first request is only part of the cost. Teams should also look at the time, tokens, and money spent before the task is finished. Comparing those numbers can show where a workflow is taking longer or costing more than expected.

Turn insights into auto routing

Once a team has identified an overkill pattern and confirmed it across task, cost, latency, and turn data, it can turn that insight into an automatic routing decision.

For example, the task view might show that much of the team’s AI usage is summarization and formatting. The model view could show that those requests are being sent to a large reasoning model, while the turns view shows that most conversations finish in a single turn. Together, these signals give the team a concrete workload to evaluate.

In addition to our updates to User Insights, the Auto Router is now available in closed beta. The Auto Router uses the conversation trajectory, task category, task complexity, and model-fit signals to automatically route requests to an appropriate model while taking cost into account.

Instead of creating a separate routing rule for every workload, customers in the beta can let the Auto Router select among the models available to their application. The router does not simply send every request to the least expensive model, but instead selects an appropriate model for the task at hand. Complex coding or research work may still need a more capable model, while simpler tasks may be handled by a faster or less expensive option.

To learn more about the Auto Router and sign up for the closed beta, read the blog post here.

The Auto Router uses the same task and conversation signals that power User Insights. The section below explains how those signals are produced.

How User Insights classifies traffic

Each conversation receives an analysis signal that can be grouped in User Insights. The signal is used for reporting and routing analysis, and is not intended to replace or expose the original request.

The categorization engine is a dedicated Cloudflare Worker that processes eligible AI Gateway logs. It examines the conversation trajectory, including user requests, assistant responses, tool calls, and tool results, and identifies the type of work being performed, such as coding, debugging, research, or summarization. It also returns a confidence score and evaluates dimensions such as task complexity, intent ambiguity, stakes, and context dependence.

The Worker returns a category that can be joined with the log metadata used by the dashboard. These signals can also be used to evaluate model fit by comparing how well candidate models suit the task against their cost. The current implementation focuses on a small set of categories that are easy to understand, rather than trying to infer every detail about a user’s work.

The pipeline follows the existing AI Gateway log architecture. Metadata is stored separately from log bodies, and the current implementation uses Durable Objects for metadata and R2 for log bodies. User Insights exposes derived categories and aggregate views. It does not turn the dashboard into a raw prompt browser. Retention of the underlying log bodies continues to follow the configured AI Gateway logging behavior, so teams should review those settings when deciding what to send through the classifier.

The classification is asynchronous, which means it happens after AI Gateway has handled the request rather than while the user is waiting for a response. AI Gateway writes the log to the existing storage path first, and the classification Worker processes it afterward. This keeps classification out of the request path and adds no latency to the user’s response.

The tradeoff is that User Insights is not a real-time view. Newly received conversations may not appear in the dashboard immediately, and analysis may trail incoming traffic by approximately one day as logs are processed and aggregated. Teams should use User Insights to identify usage patterns over time rather than monitor live request activity.

The flow looks like this:

Connect usage to users, teams, and tools

Task categories become more useful when they can be viewed by user, team, or application. AI Gateway is identity-aware, providing that context without requiring teams to build a separate reporting pipeline.

This works not only for applications that teams build themselves, but also for developer tools and agent harnesses such as Claude Code, Codex, and OpenCode. By putting AI Gateway behind Cloudflare Access, teams can connect authenticated users and sessions to their AI traffic, allowing User Insights to associate activity with the right person and conversation.

For custom applications, requests must include both a stable user_id and a session_id for User Insights analysis. The exact identity configuration and field names depend on how the application or tool is set up. The important part is to provide stable, non-sensitive user and session identifiers so usage can be grouped without putting identity data in the prompt itself.

For custom applications, the request metadata might look like this:

The request body contains the model and messages for the conversation.

With Access configured in front of AI Gateway, tools such as Claude Code, Codex, and OpenCode can inherit this identity context automatically. Cloudflare Access is available at no cost for teams with up to 50 users, making it an easy way to get started.

Get started with AI Gateway User Insights

AI usage is changing quickly. Models change, teams develop new workflows, and the right choice for one group may be the wrong choice for another.

User Insights lets teams start making smarter choices by identifying where certain models may be overkill. They can then see which users and agents are driving that usage, understand the tasks behind it, and compare the cost of completing the work.

Learn more with the AI Gateway User Insights documentation . Open AI Gateway in the Cloudflare dashboard, and use what you learn to make more targeted model and routing decisions.

Is your domain using post-quantum encryption? Now you can see for yourself

Post Syndicated from Andrew Depke original https://blog.cloudflare.com/post-quantum-visibility/

Today, we are introducing additional post-quantum (PQ) cryptography visibility tools into Cloudflare's Application Security and Logs products. You can now inspect and graph the adoption of post-quantum TLS 1.3 encryption for live traffic from directly within Logpush, Log Explorer, and the HTTP Traffic Analytics dashboard. By surfacing the key exchange algorithm negotiated on every incoming request from visitors to our platform, Cloudflare gives customers granular, per-connection telemetry to audit their post-quantum posture, assess compliance, and identify cryptographic gaps across their domains.

Cloudflare is targeting 2029 for full post-quantum security, and executing a cryptographic transition at scale requires detailed telemetry. We’ve already deployed post-quantum encryption across many of our products, including in our cloud-proxy platform and on every on-ramp and off-ramp of our SASE platform.   As many of our customers work towards quantum-readiness deadlines around 2030, we’re helping ease the transition by making post-quantum encryption the default in many of our products, sharing learnings from our internal cryptography discovery tool, and launching the new post-quantum visibility features for TLS that we’ll cover in this blog.

Bringing post-quantum visibility to the domain level

When it comes to post-quantum visibility, we already have macro-level visibility into Internet-wide post-quantum adoption in TLS through Cloudflare Radar. On Radar, we track global post-quantum encryption statistics, both when Cloudflare proxies HTTP requests from visitors (the visitor-to-Cloudflare connection) and when Cloudflare connects to origin servers (the Cloudflare-to-origin connections), as shown in this figure.

From Radar we can see that about 70% of browser-generated traffic hitting Cloudflare's network (on the visitor-to-Cloudflare connection) is protected with post-quantum encryption using hybrid ML-KEM (FIPS 203).  Meanwhile, we can see that today, just about 15% of origins that Cloudflare connects to use hybrid ML-KEM. These are aggregate numbers; the first number is aggregated across all the browser-generated traffic we see, and the second number is aggregated across all the origins we connect to.

We’ve also recently launched Automatic Key Exchange for the Cloudflare-to-origin connection, which reveals which cryptographic algorithms are supported by a given origin. This is useful because outdated configurations can cause an origin to connect to Cloudflare using classical cryptography, even if it does support a post-quantum encryption. 

While Radar and Automatic Key Exchange both provide valuable macro-level views of Internet-wide readiness, our customers have asked us to be able to go beyond aggregate numbers and dive into the behavior of individual domains.

We have long provided visibility into the TLS version used at individual domains (TLS 1.3, TLS 1.2, etc.).

But until now we have not exposed information about the cryptographic algorithms used with the TLS version used at the domain level. This means customers could not answer questions like “What fraction of traffic to my domain www.example.com is using post-quantum encryption?” This information is helpful when aiming to comply with regulatory frameworks, troubleshooting a migration to post-quantum encryption, or seeking to understand which fraction of traffic that is exposed to future quantum adversaries. Now, these questions can be answered.

Post-quantum cryptography in TLS

Before we get into the new product features, let’s do a quick review of post-quantum cryptography in TLS, so we can understand the information that the feature surfaces.

In 2024, the National Institute of Standards and Technology (NIST) stated that RSA and Elliptic Curve Cryptography (ECC) should be deprecated by 2030, and many governments and regulators have since gotten behind that deadline. That’s why today, many of our products are protected with post-quantum encryption using a cryptographic key agreement algorithm called hybrid ML-KEM. Post-quantum encryption is needed right now to stop harvest-now-decrypt-later attacks, where an adversary harvests data today and then decrypts it in the future once powerful quantum computers come online. Organizations that have data that are valuable even if decrypted in 3–10 years (public sector, defense, finance, telecom, healthcare, and others), should consider immediately protecting their traffic with post-quantum encryption.  

 In TLS 1.3, the key exchange group X25519MLKEM768 is the only recommended algorithm for post-quantum encryption. It is now the algorithm preferred by most major browsers. (Note: post-quantum encryption is not available in TLS 1.2 or any earlier version of TLS.)   If you are using Chrome, you can check the key agreement algorithm used by this webpage (or any other) by right-clicking “Inspect”, going to the “Security” tab and looking for the below:

With X25519MLKEM768 in TLS 1.3, the client and server execute both:

  • the Elliptic Curve Diffie-Hellman Key Exchange (ECDHE) over curve X25519 and
  • the post-quantum Module Lattice Key Encapsulation Mechanism (ML-KEM)

X25519 and MLKEM768 each produce a shared secret. TLS then combines those two secrets and uses the result to encrypt TLS traffic. This hybrid approach provides belt-and-suspenders security; as long as one of the two key exchanges is secure, the resulting shared secret is also secure. TLS 1.3 also supports other key exchange groups, including X25519, P-256 and P-384, all of which are just classical ECDHE over different elliptic curves; these algorithms are still used all over the web. In earlier versions of TLS you can also find key agreement based on the RSA algorithm, which is quantum-vulnerable and thankfully much less popular these days due to many known classical security problems.

But post-quantum encryption is only the first part of the story; the second part is post-quantum authentication. Once powerful quantum computers exist, we need to worry about upgrading the certificates and signatures used in TLS 1.3 away from RSA and ECC and towards post-quantum algorithms like ML-DSA. We’re actively making progress towards that goal. In fact, we recently announced that origins can use ML-DSA-44 certificates over TLS 1.3 to connect to Cloudflare, and today we announced that we’re launching a certificate authority that will support post-quantum Merkle Tree Certificates. Nevertheless, for now it remains true that post-quantum encryption with hybrid MLKEM is more broadly deployed than post-quantum authentication.

Bringing post-quantum visibility to the visitor-to-Cloudflare connection

Today we’re making it possible to see the extent to which post-quantum key agreement is used on the visitor-to-Cloudflare connection for any domain in HTTP Traffic Analytics dashboard, Logpush, and Log Explorer.

To view the TLS key exchange data on your domains, go to the Cloudflare Dashboard, and navigate to HTTP Traffic under the Analytics tab. Here you’ll get in-depth statistics about the kinds of traffic visiting your domains, now including a dedicated card for TLS Key Exchange groups on the visitor-to-Cloudflare connection. (Scroll down to find it!) Here’s a look at a TLS Key Exchange card for one of our test domains:

As you can see, the majority of the traffic to this domain uses post-quantum X25519MLKEM768 (in TLS 1.3).  We see some traffic using classical ECDHE over curve X25519 or P-256 (in TLS 1.3 or below).  The traffic labeled “None” is using either RSA key agreement (in TLS 1.2 or below) or no TLS at all. And finally we have a small number of visitors using the now-deprecated X25519Kyber768Draft00 algorithm with TLS 1.3, which we implemented back before X25519MLKEM768 was fully standardized by the Internet Engineering Task Force (IETF). We’ve waited to remove support for X25519Kyber768Draft00 until observed connections are diminishingly small, to avoid regressing clients for which this is their only way to support PQ encryption.

While we’re here, we’ll just drop a few tips about PQ-ing your traffic. If you look at your domain and find no use of X25519MLKEM768 at all, you should confirm that TLS 1.3 is enabled. In the Cloudflare dashboard, select your domain, go to SSL/TLS > Edge Certificates, and then scroll until you find the TLS 1.3 switch; switch TLS 1.3 to On. (There is no separate post-quantum setting: when TLS 1.3 is enabled and a visitor supports X25519MLKEM768, Cloudflare negotiates it automatically.) Also, if the vast majority of your traffic is over classical X25519, P-256, P-384, or None, it might be because most visitors to that domain are non-browser clients that lack support for X25519MLKEM768 and/or TLS 1.3. (Again, most major browsers do prefer to negotiate a TLS 1.3 connection with X25519MLKEM768.)

The key exchange group can now also be a filtering term in the HTTP Traffic dash. Here’s how to take a look at the traffic that is not using post-quantum encryption with X25519MLKEM768:

Analytics are great for aggregate investigations, but being able to see this information in individual log lines can be even more powerful. You can enable the new ClientTLSKeyExchangeGroup field, under the TLS category in the HTTP Requests dataset, to gain visibility into individual post-quantum key exchange in your Log Explorer and Logpush connection logs.

With this new field enabled, you’ll see it start appearing in your Logpush HTTP Request logs, like so:

Visibility to origins and more

The release of the key exchange group stats represents the first major milestone in our broader cryptographic visibility initiative. Designed for scalability, our underlying telemetry pipeline is built to ingest additional cryptographic parameters from TLS handshakes.

That’s why we’ve also surfaced the key exchange group from the Cloudflare-to-origin connection and to provide end-to-end visibility from eyeball to origin in Logpush as OriginTLSKeyExchangeGroup. (This group will be the same for all visitor connections made to that domain, which is why it's not shown in the HTTP Traffic Analytics dashboard).

And for customers that use legacy origin servers that are unlikely to support modern post-quantum cryptography, don’t despair. You can put the origin server behind a Cloudflare Tunnel, to tunnel traffic from the origin server to Cloudflare over TLS 1.3 with X25519MLKEM768, without need to upgrade the legacy origin server itself. This is what the network configuration would look like if you put your origin server behind a Cloudflare Tunnel:

Eventually we’ll be able to also surface post-quantum authentication (namely the algorithm used for certificates and signatures in TLS, including Merkle Tree Certificates) once we start to see a broader-based deployment of that technology.

Your domain has started its post-quantum journey

If your domain is behind Cloudflare, its post-quantum journey is already underway. Check HTTP Traffic Analytics dash and your logs to see the percentage of visitor connections to your domain that already use TLS 1.3 with post-quantum encryption (X25519MLKEM768).  You can also check logs to see if you’re using post-quantum encryption on the Cloudflare-to-origin connection. If your origin server is too ossified to support post-quantum cryptography, then just put it behind Cloudflare Tunnel. With the right settings and visibility, you can protect more of your traffic on Cloudflare from harvest-now-decrypt-later attacks today.

We thank Luke Valenta, Ollie Hsieh and Alex Krivit for contributions to this work.

How fast is the web? Explore billions of real-user measurements with BEACON

Post Syndicated from Ryan Townsend original https://blog.cloudflare.com/how-fast-is-the-web/

If you work in technology, you’re probably reading this on a powerful laptop or flagship mobile on robust, lightning-fast Wi-Fi. This is fantastic for building software, but often is far removed from the reality facing many who are using that software.

End users might be nursing a four-year-old budget phone, running low on battery, on a data plan that throttles after 2 GB, living with under-invested public infrastructure, or even just walking into that corner of the gym where the Wi-Fi never seems to work. Multiply this by billions of people around the world and the gap between “works on my machine” and “works for everyone” starts to widen, distorting critical decisions regarding our technology choices and priorities.

Closing the perception gap with objective data is central to our mission of helping build a better Internet, one that's fast and accessible to everyone, not just those of us using the best hardware.

That’s why today, we’re sharing a view that offers insight on how real people experience the web, by publishing the Cloudflare BEACON dataset — Browser Experience Across Cloudflare's Observed Network. Cloudflare has collected this kind of telemetry for years on behalf of our customers, giving them a customer-specific, detailed understanding of how real users experience their sites. Today, we're opening that view up to everyone.

BEACON is an anonymized dataset built from billions of real-world performance measurements across 10,000 of the largest websites on our network. It covers every major browser engine, is updated daily in Google BigQuery, and uses standards defined by the community-led RUM Archive, a publicly available Real User Monitoring (RUM) database. By expanding the footprint of that project 100-fold, BEACON gives researchers an unprecedented view of how the web performs across browsers, devices, and countries.

What BEACON reveals

The Core Web Vitals have long been the de facto standard for measuring perceived performance on the web, and BEACON reports all three:

  • Largest Contentful Paint (LCP): load time
  • Cumulative Layout Shift (CLS): visual stability
  • Interaction to Next Paint (INP): interaction responsiveness

Because we’re publishing these as full histograms rather than single averages, you can derive any percentile you like. Instead of stopping at P75 (the 75th percentile), you can examine the long tail and see where the industry still struggles to deliver fast experiences for everyone.

Who experiences a slower web?

WebKit, currently the only browser engine on iOS, performs best on these metrics overall, but that advantage is not universal. In 46 countries where WebKit represents more than 10% of traffic, its LCP, INP, or both are at least 10% worse than those of Blink-based browsers such as Chrome, Edge, and Opera. In Cambodia, for example, WebKit accounts for 17.5% of page views, but its LCP is 50% worse than Blink’s.

BEACON also includes domain industry classifications from our Intel API. Government and Politics, Health, and Safe for Kids stand out as high-performing categories, while Ads, Religion, and Weather typically perform worst:

The additional percentiles expose differences hidden by a single P75 result. In several industries, the slowest experiences fall sharply in the long tail, particularly for visual stability as measured by Cumulative Layout Shift.

What makes pages feel slow?

BEACON extends the RUM Archive standard with LCP and INP sub-parts that separate the stages of loading and responding to an interaction. We’ll also add these metrics to our Real User Monitoring (RUM) dashboard in the coming weeks. Aggregating them into the suggested ‘Good’, ‘Needs Improvement’, and ‘Poor’ thresholds helps narrow down what needs to be optimized:

LCP Sub-part

Document TTFB
(Time to First Byte)

Nothing can be rendered until we have our HTML document.

Load Delay

Is JavaScript dependence slowing discovery of our LCP candidates?

Load Duration

Is bandwidth an issue, with the LCP image/video/webfont taking a long time to download?

Render Delay

When all is ready, is there something blocking the LCP from rendering?

Good

598ms

76ms

119ms

157ms

Needs Improvement

1015ms

1049ms

199ms

437ms

Poor

1891ms

1485ms

119ms

2002ms

The query for the table above and others for every data is stored in BigQuery alongside the dataset as ‘Global LCP Sub-parts’ so you can customize it as you see fit.

The results challenge a common assumption: downloading the resource itself, such as an image, font, or video, typically contributes the least to perceived loading time. For most page views that breach the ‘Good’ threshold, the larger opportunities are discovering the LCP (load time) candidate and unblocking its render. Cloudflare customers can address some resource-discovery delays with Smart Hints.

The same workflow breaks down Interaction to Next Paint (INP), our measure of responsiveness, into input delay, processing time, and presentation delay:

INP Sub-part

Input Delay

Are our interactions waiting on the main thread becoming available?

Processing Time

Does processing the interactions themselves block the main thread?

Presentation Delay

How long does it take to paint any update to the screen?

Good

18ms

55ms

56ms

Needs Improvement

32ms

112ms

111ms

Poor

84ms

284ms

217ms

Query for above table stored as ‘Global INP Sub-parts’ in BigQuery

For the slowest interactions, JavaScript execution time covers the longest period but we also see a significant rise in presentation time, which is typically dominated by complex CSS layout recalculations. Cloudflare customers can use tools such as Zaraz to reduce the performance impact of third-party JavaScript.

How application architecture changes the picture

Speaking of JavaScript, we recently added support for Google Chrome’s new Soft Navigations API, which provides accurate LCP reporting for client-side navigations commonly used in single-page applications built with frameworks such as React, Vue, Angular, and Svelte.

LCP Percentile

P50

P75

P90

P95

Hard Navigations

791ms

1,421ms

2,636ms

4,122ms

Soft Navigations

274ms

582ms

1,169ms

1,816ms

Query for above table stored as ‘Blink – Hard vs Soft Navigations’ in BigQuery

Soft navigations render two to three times faster than hard navigations at every percentile. But they do not eliminate the cost of the initial landing page, which is often considerably heavier:

LCP Percentile

P50

P75

P90

P95

Landing Page

1,370ms

2,681ms

5,397ms

8,940ms

Query for above table stored as ‘Blink – Landing Pages’ in BigQuery

For teams choosing this architecture, it’s important to be mindful of tradeoffs: faster subsequent navigations must offset a slower first experience. If users rarely progress beyond the landing page, a heavier initial load may never pay for itself.

What can researchers discover by combining data?

Because BEACON is an open dataset, its value is not limited to the fields it contains. Researchers can join it with other sources to explore new questions. For example, combining BEACON with the World Bank Group’s measure of GDP per capita reveals how economic conditions correlate with web performance by country:

Cloudflare Radar, our public data insights and visualizations platform, will start using this approach in a new Web Performance section on Radar, featuring correlations of their Internet Quality Index (IQI) data with BEACON data. IQI is an aggregation of the performance benchmarking data that powers our bi-annual network performance updates.

Pairing BEACON and IQI is particularly compelling because it splits the user experience into its two most influential components: the performance of the website a user is visiting, and the performance of the eyeball network getting them there. Both affect how quickly the page will load, and together they determine whether a visit to a website feels painful or seamless.

Early analysis shows the two tend to move together: good web performance usually coincides with good network quality, and vice versa. In the above graphs we see that the higher the bandwidth, the faster the perceived load time (LCP). For example in Europe, the bandwidth is higher relative to other continents, while the LCP is higher overall with the lower end.

The relationship between bandwidth and LCP was expected, but when comparing IQI to Transfer Size we saw something surprising. We would expect that transfer size would be uniform across continents — after all, the content of the sites are typically the same. However, see that Africa has a noticeably smaller transfer size, suggesting less content being downloaded by these users. Although we can’t be sure of the cause, we can observe that in the IQI data Africa has lower bandwidth, which suggests that businesses on the continent are adapting their websites to optimize towards the constraints of network conditions. High-quality eyeball networks are also potentially more forgiving to poorly-optimized websites, while a slow one exacerbates bottlenecks. Each of these hypotheses are potential directions for future analysis.

The new Web Performance section will explore how common these patterns are, and in particular how often one half of the experience cancels out the gains made by the other. Follow our progress on Radar.

We’ll continue to introduce more metrics and more dimensions over time, and we welcome requests for data you’d like to see next.

How we process all this data and make it useful

Anonymization

Publicizing a real-world dataset at this scale brings with it responsibility for privacy. Our Real User Monitoring (RUM) product is already built to be privacy-first, and for BEACON, we also strip out any potential customer website identifiers such as the domain name and URL paths. Ultimately, the community gains valuable insight without compromising the trust of the people and businesses behind it.

Normalization

For the primary table, including all websites from our data would lead to one of two problems:

  1. The largest sites would dominate the data by traffic volume, skewing performance metrics towards their architecture, visitor profiles etc., or:
  2. If we instead normalize every site down to the traffic volume smallest website, that would drastically reduce the overall number of records in the data.

These two extremes made it necessary to scope the dataset to the greatest number of the largest websites on our network to provide maximum diversity across architectures, technologies, geography, and more, all while retaining the total beacon count after normalizing. We found 10,000 to be a good balance: a globally representative sample with enough volume in the 10,000th that when we normalize the data down to their level, the overall dataset still represents billions of daily records collectively.

Aggregation

Finally, we aggregate records together where they share dimensions such as country, operating system, browser, and connection protocol, and discard any records with fewer than five data points to further guarantee no individual or specific site can be identified.

How to get access and contribute

BEACON is publicly available on Google BigQuery. We’ve included queries for all the data included in this post as examples you can adapt for your own analysis, and the RUM Archive website includes further documentation too.

We’d love to hear what you discover. Share your findings in our community forum or on Discord.

BEACON makes it possible to study web performance at a scale and level of geographic and browser diversity that has not previously been publicly available. We hope researchers, browser vendors, developers, and standards groups use it to identify where the web falls short and help make fast experiences available to everyone.

A special shout out to Cloudflare’s 1,111 intern project. This couldn’t have happened without the hard work of two of our wonderful summer interns, taking the initial idea through to what you see today. Their contributions were instrumental in launching this project. Thanks Chisara Duru and Tong Zhou!

AWS Weekly Roundup: Welcome DuckLabs to the team, Agentic Resource Discovery (ARD), and more (August 31, 2026)

Post Syndicated from Daniel Abib original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-welcome-ducklabs-to-the-team-agentic-resource-discovery-ard-and-more-august-31-2026/

The news that interested me the most last week was the DuckLabs acquisition. AWS has signed a definitive agreement to acquire DuckLabs, the Amsterdam-based company behind DuckDB, the popular open source analytical database that runs in-process and executes SQL directly against files like Parquet, CSV, and JSON. DuckDB stays open source under its independent foundation and the MIT license, and over time AWS plans to combine its speed at everyday queries with the enterprise scale of services like Amazon S3, Amazon Redshift, and Amazon Athena.

Co-founded by Hannes Mühleisen and Mark Raasveldt, DuckDB runs locally or on Amazon S3, which makes it remarkably fast for the everyday queries (a terabyte or less) that make up the bulk of real-world analytics. It also happens to pair beautifully with AI agents, which “poke” and experiment their way through data much like humans do. The co-founders will continue leading its technical direction while AWS combines DuckDB’s speed with analytics services like Amazon EMR, AWS Glue, and Amazon SageMaker. For the bigger picture on why this matters, Andy Warfield, Vice President and Distinguished Engineer shared his thoughts on the post DuckDB and the changing physics of analytics on All Things Distributed.

Now, let’s get into this week’s AWS news…

Last week’s launches
Here are some launches and updates from this past week that caught my attention:

  • Amazon ECS now automatically detects and recovers container instances that lose agent connectivity – Amazon ECS now continuously monitors agent connectivity to the control plane and surfaces a new AGENT_CONNECTIVITY health event across AWS Fargate, Amazon ECS Managed Instances, and Amazon ECS on EC2. On Fargate and Managed Instances, ECS handles recovery automatically, draining tasks, launching replacements, and deregistering the impaired instance. On EC2, you can wire the event into your own workflow. Available at no additional cost in all AWS Commercial and AWS GovCloud (US) Regions.
  • AWS Lambda introduces public preview runtimes, starting with Node.js 26 and Python 3.15 – You can now test upcoming Lambda runtimes before they reach general availability. Preview runtimes use the same identifier as the eventual GA version, so your functions graduate automatically with no action required. Third-party tools and deployment frameworks can also validate compatibility ahead of GA. Not meant for production yet (breaking changes are possible), but a great way to get ahead of your next upgrade. Available in all AWS commercial, AWS GovCloud (US), and China Regions.
  • AWS IoT Core adds a native InfluxDB rule action – You can now route time-series data from your IoT devices straight into InfluxDB (Amazon Timestream-managed or self-hosted) without writing custom code or standing up an intermediate service. IoT Core formats data into InfluxDB’s line protocol and supports device-side and server-side batching. Available in all AWS Regions where Amazon Timestream for InfluxDB is offered.
  • Amazon GameLift Servers now includes enhanced DDoS protection – Your game servers now get automatic protection against network and transport layer (layers 3 and 4) DDoS attacks – UDP reflection, SYN floods, and similar vectors – with nothing to enable or opt into. Built on top of AWS Shield Standard with gaming-optimized traffic shaping, it turns on the moment your servers start running (Server SDK 5) at no extra cost. It’s available in all supported GameLift Servers Regions except China (Beijing) and China (Ningxia).
  • Amazon SageMaker HyperPod expands support for Ray – You can now run Ray workloads on SageMaker HyperPod with built-in observability, resilient training, and accelerated inference. Create and manage Ray clusters from Amazon SageMaker Studio, attach JupyterLab or your local IDE so a multi-node cluster behaves like a local dev environment, and get auto-provisioned Grafana dashboards. Node auto recovery, hung job detection, and tiered checkpointing keep large training runs healthy, while Ray Serve adds a tiered KV cache for inference. Your existing open source Ray code runs unchanged. Available for HyperPod clusters orchestrated by Amazon EKS.

For a full list of AWS announcements, be sure to keep an eye on the What’s New with AWS page.

Other AWS news
Here are some additional posts and resources that you might find interesting:

  • Happy 20th birthday, Amazon EC2! – Amazon EC2 turns 20. Channy Yun looks back at how EC2 grew from a single m1.small instance type in one Region to more than 1,200 instance types across 39 Regions, along with the custom silicon journey from the first Graviton to Graviton5 and Trainium3. A fun and worthwhile read on the service that still underpins so much of AWS – including Amazon ECS, Amazon EKS, AWS Lambda, Amazon SageMaker, and Amazon Bedrock.
  • Agentic Resource Discovery (ARD): an open specification for agent discovery – As organizations scale up agents, tools, and MCP servers, those resources end up scattered across clouds, on-premises infrastructure, and SaaS platforms – each with its own registry and metadata. ARD is a new open specification (Apache 2.0) that defines a common way to describe and discover agentic resources, so publishers “describe once” and consumers “discover everywhere” – think DNS, but for agents. AWS contributed feedback but doesn’t own the spec, and it complements the AWS Agent Registry by letting you federate across catalogs without migrating.
  • Get started with the Agent Toolkit for AWS in the AWS CLI – A single AWS CLI command (aws configure agent-toolkit) now equips AI coding agents like Kiro, Claude Code, Codex, and Cursor with curated, up-to-date AWS knowledge and a secure connection to thousands of AWS APIs through the AWS MCP Server. If you build with an AI coding assistant, this helps it choose the right services, use modern APIs, and follow security best practices – so it gets AWS code right more often the first time.

Upcoming AWS events
Check your calendar and sign up for upcoming AWS events:

  • AWS Summits – Free in-person events where builders come together to learn, connect, and explore the latest in cloud and AI. Upcoming stops include Zurich (September 2), São Paulo (September 3), Tel Aviv (September 10), and Dubai (September 30). Can’t attend in person? You can stream sessions through the Global Livestream and On-Demand Hub. I’ll be presenting two sessions on generative AI and Amazon Bedrock at the São Paulo Summit – if you’re there, come say hello.
  • AWS Community Days – Community-led conferences where content is planned, sourced, and delivered by community leaders. Upcoming events include JAWS SONIC 2026 in Tokyo (September 5) and Warsaw, Poland (September 8).

Join the AWS Builder Center to connect with builders, share solutions, and access content that supports your development. Browse here for upcoming AWS-led in-person and virtual events and developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Daniel Abib

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

AWS and DuckLabs: Building the future of analytics together

Post Syndicated from Mai-Lan Tomsen Bukovec original https://aws.amazon.com/blogs/big-data/aws-and-ducklabs-building-the-future-of-analytics-together/

Today we are announcing that Amazon has signed a definitive agreement to acquire DuckLabs, the Amsterdam-based company behind the open-source analytical database DuckDB. We expect the transaction to close shortly, subject to customary closing conditions. Hannes Mühleisen and Mark Raasveldt, who created DuckDB and co-founded DuckLabs, will continue leading the team and the open-source project’s technical direction as part of AWS. The DuckDB open-source project will also continue to be driven by the DuckLabs team, remain open source under the independent Foundation (the non-profit that oversees DuckDB), and available under the MIT license as it does today (see DuckLabs blog).

Data has always been a core asset and differentiator for companies. That is true now more than ever, as organizations use their data to customize inference and build AI agents. For 20 years AWS has driven the frontier of data, starting with the launch of Amazon S3 to create data lakes for every business, the first cloud analytics service in Amazon EMR, the first cloud data warehouse with Amazon Redshift and the many capabilities that we have introduced with Athena, Glue ETL, etc. We continue innovating for AWS customers on the data frontier including providing Apache Iceberg capabilities directly in S3 Tables, vector storage in the data lake and our new optimized Graviton-based Redshift clusters.

DuckDB has also been at the forefront of changing how the world works with data. Hannes and Mark started DuckDB while at Centrum Wiskunde & Informatica (CWI), the national research institute in the Netherlands that also invented Python. The founders of DuckDB realized that older databases and analytics engines like Spark focused on performance for very large data processing but didn’t have an effective way to “scale down” to smaller size data queries that form the backbone of what most customers do with SQL analytics.

DuckDB set out to solve the problem of blazingly fast performance for the 90%+ of data queries in the world today, that often runs 1 terabyte of data or less as part of analysis and dashboarding. DuckDB’s architecture is based on that core premise of “make the everyday SQL query super fast” so DuckDB runs in-process to other applications which simplifies and speeds up data exchange with the application. DuckDB gets big performance gains from its vectorized execution because it does not require a heavy compiler to run simple statements like SELECT * FROM table. And what works for everyday queries also (unsurprisingly) works very well for agents because agents behave a lot like people when interacting with data. They poke. They experiment. They run exploratory analysis on small data sets before figuring out what they really want to do. DuckDB ends up being naturally optimized for AI agents to use. What started as an academic project is now widely adopted across data engineering, data science, analytics, and now AI agents, for its simplicity of use and raw performance. We plan to combine the superpower of DuckDB at everyday queries of a terabyte or less with the proven exabyte-plus enterprise scale of S3 and our AWS analytics services of Redshift, Athena, EMR, Glue-ETL, and SageMaker platform which power analytics across hundreds of terabytes to petabyte of data. Andy Warfield, Distinguished Engineer at AWS, talks about DuckDB and the Changing Physics of Analytics in Werner Vogel’s All Things Distributed blog.

Our customers use DuckDB today with AWS services and tell us how much they love it for its speed and simplicity. For example, DuckDB today executes SQL directly against external files, such as Parquet, CSV, and JSON, stored locally or on cloud storage like S3 for unparalleled performance and significantly lower cost. DuckDB can also run in-process to AWS Lambda functions.

David Feng, Executive Director, Scientific Computing at Allen Institute, said “The Allen Institute accelerates science for a healthier world by tackling the biggest questions in biology at a large scale, and that involves extensive analysis of large, multimodal data. We started using DuckDB to analyze terabytes of scientific data in 2025 and love it. We are storing data in S3 for realtime quality control and analysis of neurophysiology and behavior data, critical to driving the next data acquisition. Queries that took minutes now come back in less than a second, enabling completely new ways of interacting with data.”

We are excited to make DuckDB applications run best on AWS, and will continue to invest in deep integration between DuckDB and our building block services.

We are also using DuckDB in our own AWS infrastructure. When Amazon Quick wanted to augment the performance of their custom dashboarding engine, they picked DuckDB to query data in S3 Tables. The Quick team found that the DuckDB engine scales effortlessly with the number of CPUs, and its single library can easily plug into the internal Quick control plane subsystems. Since we launched Quick in October 2025, we have processed over 2.5B queries using our custom Quick query engine with the DuckDB integrations and optimizations. These DuckDB integrations and optimizations helped Amazon Quick reduce average query latency by 30%. We are going to look at how we can integrate DuckDB’s performance and simplicity in our other AWS services across data and analytics.

Stay tuned for more about how DuckLabs and AWS will reinvent the frontier of data together for applications, data engineers, and AI, meeting customers where they are today and giving them the benefits of DuckDB’s innovation within AWS.


About the author

Mai-Lan Tomsen Bukovec

Mai-Lan Tomsen Bukovec, Technology Vice President at AWS, leads the Amazon cloud data services that millions of AWS customers rely on for digital transformations, business analytics, machine learning, generative AI, and next generation customer experiences. With over 25 years of experience in the technology industry, Mai-Lan is a pioneer in helping customers take advantage of cloud-based technologies to transform their businesses.

AWS Glue 6.0 now available with 30% lower price and full Apache Iceberg v3 support

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-glue-6-0-now-available-with-30-lower-price-and-full-apache-iceberg-v3-support/

Today, we are announcing the general availability of AWS Glue 6.0, delivering 30% lower pricing than previous AWS Glue versions and introducing full support for Apache Iceberg v3 features. AWS Glue 6.0 is built on a fully modernized runtime, Apache Spark 4.1, Python 3.12, and Scala 2.13, delivering faster performance.

With this release, AWS Glue provides the most complete Iceberg v3 implementation on any fully serverless managed Spark service, along with new capabilities that simplify ETL authoring, improve PySpark performance, and enable real-time streaming with single-digit millisecond latency.

What is new in AWS Glue 6.0
AWS Glue 6.0 delivers the complete Apache Iceberg v3 specification, built on Iceberg 1.11.0. The headline feature is the VARIANT data type with shredding support, which achieves faster query read performance compared to traditional string data type columns for semi-structured data.

With VARIANT shredding, you can store and query JSON, logs, and event data without flattening schemas, eliminating duplicate data copies, custom parsing code, and pipeline breakage when schemas change. This capability transforms how teams handle semi-structured data at scale.

Additional Iceberg v3 capabilities include:

  • Geometry and Geography data types: Enable native spatial processing for GIS analytics, location intelligence, and geospatial data pipelines directly on managed Spark.
  • Nanosecond-precision timestamps: Support IoT sensor data, scientific computing, and high-frequency financial workloads that require precision beyond standard milliseconds.
  • Unknown type handling: Process data with unexpected or evolving schemas without pipeline failures, providing resilience against upstream schema changes.

AWS Glue 6.0 also includes most significant upgrade in Spark 4.1, the modern runtime engine:

  • Spark declarative pipelines: Spark Declarative Pipelines introduces a simplified approach to ETL authoring. Data engineers declare transformations, specifying what data should look like, while the engine automatically determines execution order and optimization. This reduces the complexity of pipeline development and eliminates manual orchestration overhead.
  • Arrow-native Python UDFs and UDTFs: AWS Glue 6.0 introduces Arrow-native execution for Python User-Defined Functions (UDFs) and User-Defined Table Functions (UDTFs). This eliminates serialization overhead between Python and the JVM, improving PySpark performance for complex transformations.
  • Real-time streaming mode: For stateless streaming use cases, AWS Glue 6.0 introduces a real-time streaming mode that achieves single-digit millisecond latency. Built on Spark 4.1’s Real-Time Mode with Glue-optimized execution, this capability supports real-time event processing, low-latency data transformation pipelines, and time-sensitive data routing.

Getting started with AWS Glue 6.0
No API changes are required to use AWS Glue 6.0. You can select the new version using the existing --glue-version parameter in the create-job or update-job APIs through AWS Command Line Interface (AWS CLI), AWS SDK, AWS Glue Studio, Amazon SageMaker Unified Studio, and your preferred IDE.

To get started with AWS Glue 6.0 jobs in the AWS Glue Studio console, open the AWS Glue job and on the Job Details tab, choose the version Glue 6.0 – Supports Spark 4.1, Scala 2, Python 3. You can create new AWS Glue jobs on AWS Glue 6.0 to get the benefit from the improvements, or migrate your existing AWS Glue jobs.

To start using AWS Glue 6.0 on an AWS Glue Studio notebook or an interactive session through a Jupyter notebook, set 6.0 in the %glue_version magic. You can also upgrade existing jobs to Glue 6.0 using the Spark upgrade agent on AWS Glue Studio or use the auto-upgrade feature in their existing Glue jobs to automatically upgrade them to Glue 6.0.

To learn more, visit the AWS Glue 6.0 version detail and Migrating AWS Glue for Spark jobs to AWS Glue version 6.0 in the AWS documentation.

Now available
AWS Glue 6.0 is generally available today in all AWS Regions where AWS Glue operates. For Regional availability and a future roadmap, visit the AWS Capabilities by Region. If you want to call APIs, search documentation, find regional availability, and check troubleshooting about this new feature, try using the AWS MCP Server and plugins with your preferred AI tool.

You pay an hourly rate, billed by the second, for crawlers (discovering data) and extract, transform, and load (ETL) jobs (processing and loading data). For the AWS Glue Data Catalog, you pay a simplified monthly fee for storing and accessing the metadata. The first million objects stored are free, and the first million accesses are free. To learn more, visit AWS Glue Pricing page.

Give it a try in the AWS Glue Studio console, and send feedback to AWS re:Post for AWS Glue or through your usual AWS support contacts.

— Channy

How AI is transforming analytics at Grab

Post Syndicated from Grab Tech original https://engineering.grab.com/how-ai-is-transforming-analytics

Introduction

At Grab, analytics sits close to almost every decision that matters. Our north star is the democratisation of intelligence, ensuring that anyone making a business call has immediate access to trustworthy answers.

Over the last two years, model capability has crossed a threshold enabling this shift. Agents now do in minutes what used to take a week: preparing the data, writing queries, running deep analysis and developing insights for business opportunities, designing experiments and interpreting the results, drafting the commentary that follows, and more. Our throughput is no longer rate-limited by how fast an individual can write code, build a deck, or run a deep-dive. It is rate-limited by how fast we can frame the right problem, judge the right answer, and influence the right decision.

As autonomy climbs, an analyst’s impact moves from producing the artefact to owning the question and the call behind it, and the role evolves to become part builder, part advisor, part strategist, owning the loop rather than running it. That unlocks two things at once: work we already do, faster and at lower marginal cost, and work we could never staff before, sitting beside every product manager, business owner, and operator at the moment they decide.

The ladder

We were heavily inspired by Dan Shapiro’s framing of five levels for AI coding. We use a similar ladder that defines how much of the loop an agent should own and where human judgement stays for every analytics loop.

One distinction runs across every level: who owns the loop, and where human judgement is required.

Level What Human role Agent role
L2 AI-Assisted Owns and executes every step; uses AI to draft, suggest, summarise Drafts SQL, suggests a visualisation
L3 Human plans, agent owns steps, human reviews Frames the question, picks the metric, the segment, and the comparison frame, reviews evidence, owns the recommendation Discovers data, writes and runs the query, sanity checks, drafts the write-up, flags caveats
L4 Agent plans, agent owns workflows, human reviews Sets intent and guardrails; reviews at gates (anomaly, novel scope, sensitive cut); owns the stakeholder relationship and sign-off Orchestrates discovery through query, analysis, validation, narrative and publish; runs validation, escalates exceptions
L5 End-to-end autonomous Sets objectives, quality bars, risk thresholds, escalation rules; reviews exceptions only Detects anomalies and opportunities, runs the loop, surfaces insight, evolves the metric layer, context and skills

Human judgement remains at every level, and autonomy never removes accountability. Humans own problem framing, canonical metric definitions, the causal story behind a move, business-case assumptions, the go/no-go, and the stakeholder relationship. A higher level means more of the mechanical loop sits with the agent and more human attention concentrates on the ambiguous, high-stakes work.

Making the climb

Five core capabilities move a workflow up the ladder. They also gate the climb in order: L3 needs execution and certified context, L4 needs gates and agentic review good enough that reviewing only at gates is honest, L5 needs a learning loop that closes.

  • Execution: A stack that runs the loop end to end rather than a notebook/workflow a human drives.
  • Knowledge: Metrics certified at the right grain, discoverable in our catalogue, grounded in context an agent can read. Ambiguous definitions cause most analytics slop.
  • Control: Repeatable expectations become mechanical checks, while human review handles what a rule cannot.
  • Review and governance: Agents check their own output against the gates and escalate on defined triggers. We govern definitions, targets, risk and exceptions.
  • Learning: When an agent fails the same way twice, we encode the fix into context documents, golden datasets, evals and gates.

What this looks like in practice

What follows is a set of explorations from the last two years. Some run in production today, while others are still teaching us where the limits are.

Loops that run end to end

Spartan is our end-to-end agentic analytics workflow, embedded across surface areas (like Slack), and most of its usage comes from people who are not analysts. On any given day, the Slack channel enables a range of analytics actions: from ads salespeople pulling spend breakdowns for a named merchant, to campaign managers sizing audiences for a target segment, and country teams asking why a number moved week on week. All of it in plain business language.

Figure 1. Index architecture across our knowledge base.

Two requests from July best demonstrate how it works. A commercial manager asked why revenue fell in the Philippines mid-market segment in the last two weeks of June. Separately, a product manager asked for a summary of a frequency-cap experiment on the ads surface. Both arrived as natural language questions in Slack and took entirely different routes through the system.

The router reads the first as a root-cause question and sends it down the diagnostic path. It identifies the best analysis framework for ads revenue, which is codified knowledge of how the metrics in that domain relate to each other, which dimensions are worth decomposing, and what counts as a meaningful move. Then it works through segment, market and campaign type against certified metrics to isolate what changed. The second question never touches the data lake. The router reads it as an experiment question, selects the experiment skill, pulls the pre-computed scorecard and the test’s own metadata from our experiment platform, and summarises the read rather than recomputing it. This is powered through 50+ skills and 120+ analysis frameworks that sit behind that routing decision. Underlying that is an index that tells the agent what to search, context that tells it how to query, and a framework that tells it how to think. Because the frameworks are shared rather than living in an analyst’s head, the interpretation compounds instead of being re-derived every time someone asks.

The second example of such a loop is Scarlet, which powers near-self-healing pipelines (L4). When a pipeline fails, an agent runs the root-cause analysis, triages, and then either fixes it or hands it to the team that owns the upstream problem. It escalates when the failure sits outside its documented runbooks or the pre-defined gates fire.

Figure 2. Scarlet in action on Slack.

Context that maintains itself

Context sets an agent’s ceiling. An agent that does not know a metric’s grain, its exclusions, and its caveats will guess and confidently produce wrong outputs at speed and at scale.

Realising the criticality of this, we have dedicated platform investment, as well as dedicated functional bandwidth to generate context docs.

Figure 3. ContextIQ.

Context goes out of date faster than anyone maintains it by hand, so we build the maintenance into our workflows. We built ContextIQ, and its Context Lifecycle Manager, to treat context as something with a lifecycle rather than a document somebody wrote once. A newer skill of ours reads an instrumentation spec alongside the existing context, proposes the SQL changes that follow from it, and updates the context document in the same pass. We work the problem from the other direction too. When we categorise an agent failure in production, we patch the context document behind it.

Two analysts recently used our internal agents to understand how the packaging fee is stored as a configuration. Having found the answer, the agent opened a merge request that committed both a certified-context table reference and a golden-dataset test case, so the next agent to ask the same question would find the answer already documented and the check already in place. One of the analysts spotted a false positive in it. The agent corrected itself and reopened the merge request. That is the learning capability working as designed, and it happened without anyone setting out to demonstrate it.

Loops that run unattended

The step from L3 to L4 is mostly the step from interactive to scheduled, and it is where we go down the path of autonomous execution, because no human is watching at the moment the work runs.

We have built root-cause analysis (RCA) as a platform capability, and it powers our automated metric and OKR commentaries, which are published through automated agents (configurable cadence). It judges whether a move is meaningful against standard deviation over six months and year on year, walks the metric tree to find which country, segment or funnel stage carried it, and correlates the operational metrics that moved alongside. Importantly, it also scans internal context for what teams changed on the ground, such as delivery fee and incentive moves, merchant visibility shifts, and experiments shipped in the same period. It also compares the movement against the same period in the previous year, which separates a seasonal effect from a real one and enables it to report a Songkran (Thai New Year) dip as amplified rather than merely expected. All of it is grounded in our own context documents, which keeps the narrative about the business rather than generic model output. The analytics owner is tagged on every report, and edits sync back so corrections land in the system.

Figure 4. OKR commentary shared through RCA agent.

Analysts as builders

The clearest evidence that our centre of gravity has moved is BriX, an internal portal we built and run ourselves.

Figure 5. Home page of BriX.

The premise is to configure once, host everywhere. We configure a system prompt, a set of context files, a model, the MCP connections and an interface once, and what comes out is a purpose-built analytics surface for a particular team or job. Each one inherits certified data, permissions and reusable agent skills rather than being wired up from scratch, and it runs wherever the work already happens: in Slack, invoked from inside an IDE, or on a schedule with nobody watching. We have grown usage more than 10x since September 2025, with strong retention, and every function at Grab now has users on it. Our aim is to put L3 workflows in the hands of people who are not advanced users.

We run it without a product manager, a technical programme manager or a designer. Our data engineers own the product, the platform, the support queue and the eval loop, with Claude Design doing the interface work and the builders triaging their own bugs. In the first half of this year, they shipped 31 production deployments, 283 merge requests and 60 features.

Three of our apps show the range:

  • Insights Lab is the general-purpose surface: a stakeholder asks for a metric, a breakdown or a root-cause in natural language, and the agent loads a specialist skill and answers off certified metrics rather than from memory.
  • We built Funnelytics to enable easy understanding of our consumer funnels. A funnel question used to mean an analyst writing the query and then assembling the view in Tableau or Power BI, and doing it again the next time someone wanted a slightly different path through the app. Now a stakeholder picks the events they care about and Funnelytics queries the raw event stream, builds the Sankey and funnel views, and writes the summary. If they cannot find the right instrumentation, which happens often on products still being redesigned, a live debugger lets them tap through the app on their own phone and watch the events fire.
  • Monte (like Monte Carlo) runs simulations to put a probability on a business outcome. You give each uncertain input a range rather than a single value, and it runs ten thousand scenarios to return the likelihood of hitting a target.
Figure 6. Interface of Insights Lab and Funnelytics.

Outside the portal, the same instinct shows up in smaller ways. Our analysts have been building more bespoke tools that enable better workflows for themselves and stakeholders.

The path forward

In February, 44% of the tickets our analysts closed were mechanical (data preparation, alerting, reporting); by June, that share had fallen to 30%. That capacity was redirected to other higher-leverage work, such as building new workflows to enable stakeholder self-serve, as well as more time spent on generating deeper insights for business opportunities.

Figure 7. Comparison of percentage of tickets closed in Q1 vs Q2 2026.

Importantly, our cycle times reduced by ~33%.

Figure 8. Comparison of time taken to resolve a ticket in Q1 vs Q2 2026.

The sharpest version of this sits in a Slack channel where self-serve agents are enabled. In March, an analyst had to step into half of them; by May, it was under a quarter. The share answered with no human involvement rose from 53% to 67% for metric questions, 63% to 90% for data pulls, and 50% to 81% for SQL requests. Just under three in four of the threads were started by someone outside the analytics team, and 85% of them got a first response inside a minute. Nearly every thread is logged as a ticket on the team’s board, and roughly two-thirds of the data exploration tickets on that board now arrive through the channel rather than through an analyst, and are solved by our data agents. For the ~230 tickets that arrived via the channel, if we apply a conservative assumption of 1–2 days per ticket, that is 230 to 470 business days of stakeholder asks that would have been in the backlog.

None of these arrived on a roadmap. They came from analysts who saw a loop worth automating and built it, which is why the climb is uneven. These have been strong proof points for us to believe our investments are working, and many of these workflows are starting to operate at scale. We will keep experimenting and iterating, and we expect to get a fair amount of it wrong. An analyst who owns a loop, sets its quality bar and reviews its exceptions is doing a different job from one who answers questions. Most of our team is somewhere in that transition today, and we truly believe it is changing what analytics is at Grab.

Join us

Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors. Serving over 900 cities in eight Southeast Asian countries: Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam. Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. We operate supermarkets in Malaysia under Jaya Grocer and Everrise, which enables us to bring the convenience of on-demand grocery delivery to more consumers in the country. As part of our financial services offerings, we also provide digital banking services through GXS Bank in Singapore and GXBank in Malaysia. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line. We aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!

Modeling Device Capabilities for Analytics

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/modeling-device-capabilities-for-analytics-e7607acebde8

by Aarti Laddha, Richard Diaz-Cool, Rishika Idnani, Venkatesh Selveraj

Netflix supports a vast and evolving set of features and content types, ranging from 4K streaming and immersive audio to live streaming and cloud gaming, across a diverse ecosystem of devices. However, not all devices are created equal. Hardware limitations such as available RAM, CPU cores, display capabilities, or platform support mean that some features cannot be supported on certain device models. To ensure the best possible user experience, we rely on a deep understanding of device capabilities. We have invested in building a comprehensive device capability data model and integrating feature flags from internal systems, paving the way for smarter, more granular feature management across our global device landscape. This approach helps us identify bottlenecks in feature penetration and accelerates the pace of innovation.

We have designed our data storage and modeling strategies to efficiently support analytics at scale. We use a cumulative table to process information about the device’s capabilities. This table is structured to efficiently capture the latest state of each device and its associated capabilities (like Screen resolutions, Video Profiles Supported, Surround Sound, RAM size etc) making it ideal for analytics and reporting use cases.

{
"Screen Height": ["720"],
"Screen Width": ["1280"],
"Video Profiles":
[
"playready",
"hevc",
],
}

For aggregate analytics, we leverage a histogram table that captures active device counts over the past 28 days, broken down by device model and software version. This table also records the number of devices supporting specific capabilities, enabling detailed distribution analysis. One use case for this histogram data is to analyze the distribution of external display capabilities attached to streaming sticks. For example, the histogram below shows that out of total X number of devices, all supported the HD profile (playready), while only 20% devices supported the UHD profile (hevc).

{
"Video Profiles": {
"playready": 100%, # HD profile
"hevc": 20% # UHD profile
}
}

We have built analytical products that leverage these datasets to provide a comprehensive view of feature reach such as 4K Ultra HD, Netflix Spatial Audio, Cloud Gaming and the latest UI. By relying on data-driven insights, we can make informed decisions about which features to enable on specific devices, ensuring both performance and reliability.


Modeling Device Capabilities for Analytics was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.
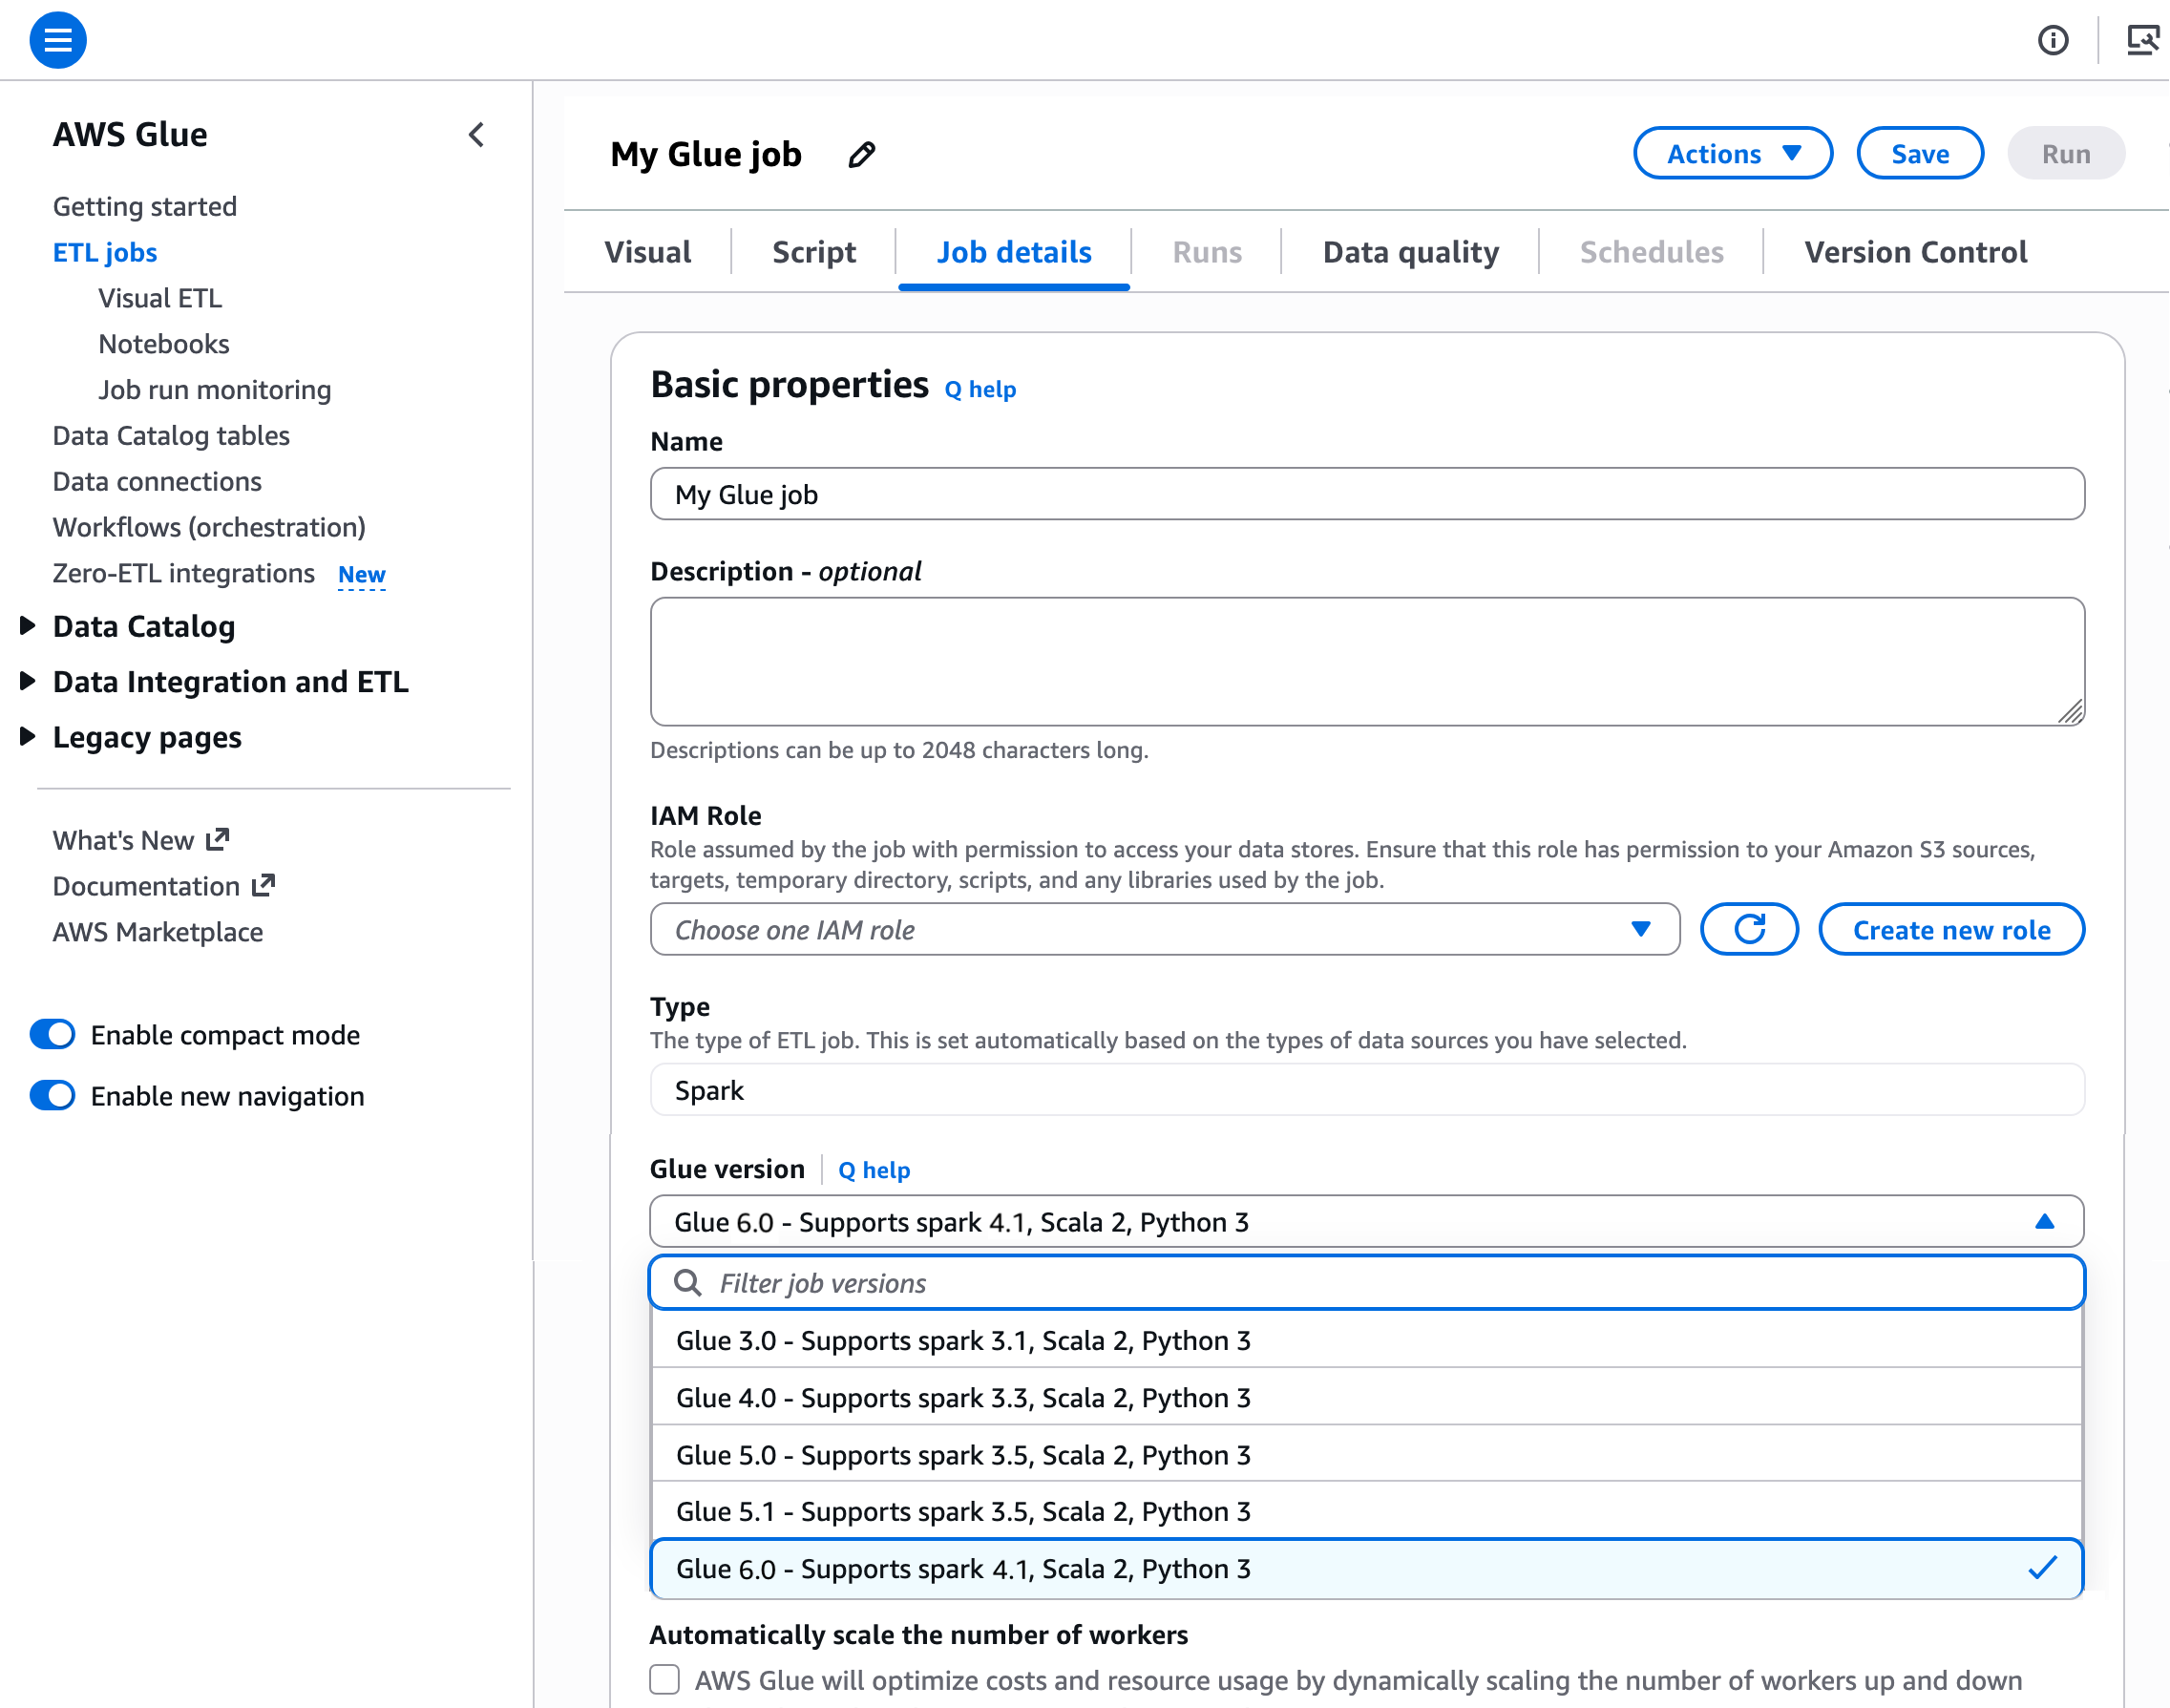
How MAPFRE USA modernized fraud claims with Amazon EMR Serverless

Post Syndicated from Lijan Kuniyil original https://aws.amazon.com/blogs/architecture/how-mapfre-usa-modernized-fraud-claims-with-amazon-emr-serverless/

Insurance fraud remains a significant challenge for the insurance industry. Fraudulent claims can increase loss costs, reduce trust, and consume investigation capacity that could otherwise be focused on serving customers. Traditional fraud detection approaches typically rely on rules-based controls, manual investigation triggers, historical claim patterns, and structured-data-only analysis. These approaches are useful for known fraud patterns, but they can struggle to detect sophisticated fraud rings or hidden relationships across claimants, policies, vehicles, providers, addresses, and prior suspicious activities.

MAPFRE USA is a top-rated auto and home insurer in Massachusetts, serving customers in 11 states nationwide. Our coverage includes auto, home, motorcycle, watercraft, business insurance, and more. As part of MAPFRE Group, we’re a worldwide leader serving over 31.1 million customers in more than 100 countries with a team of 31,000 employees. In collaboration with AWS and Neo4j, MAPFRE USA modernized its fraud prevention capabilities by combining graph-based features with machine learning (ML) models deployed on AWS. This initiative focused initially on Massachusetts auto insurance and later expanded to home insurance. It has delivered significant business impact, exceeding $5 million in net present value (NPV) over five years, with realized savings already outperforming projections.

In this post, we share how MAPFRE USA designed and implemented this solution, highlight the technical architecture running on AWS, specifically the MAPFRE data platform called Atenea, and explore lessons learned that can apply to other industries facing complex fraud challenges.

Business challenge

Fraudulent claims aren’t always isolated events. They often involve hidden networks of policyholders, vehicles, providers, and prior suspicious activities. Detecting these complex relationships requires going beyond traditional structured data analysis.

MAPFRE set out with a clear goal:

  • Goal: Improve fraud detection accuracy and claims handling efficiency.
  • Key performance indicator (KPI): Identify fraudulent claims missed by traditional methods.
  • Approach: Develop several ML models using both traditional structured data and 54 graph-based features derived from claim relationships.
  • Deployment: Integrate with Guidewire Claims, so front-line adjusters automatically receive fraud alerts with explanations.

Each flagged claim exposure generates a Guidewire activity showing the top three model drivers, helping investigators understand why the claim was flagged and act quickly.

Technical solution on AWS (Atenea data platform)

The fraud detection platform is built on a modern data architecture on AWS, designed to scale efficiently and support long-term governance.

At its core, the solution uses Apache Iceberg tables stored on Amazon Simple Storage Service (Amazon S3), with metadata managed through the AWS Glue Data Catalog and access governed through AWS Lake Formation as part of the Atenea lakehouse governance model. The platform feature store is implemented through feature-store-managed Iceberg tables that manage model features, predictions, and Guidewire activities. The implementation is structured across three logical layers:

  • Silver layer: Iceberg tables that contain source data from each of the sources. Used as the initial consumption point of the platform.
  • Gold layer: Iceberg tables storing intermediate data, such as unified Guidewire activity logs, Auto features, and Home features.
  • Platinum layer: Feature Store-managed Iceberg tables containing encoded features and model predictions, making them reusable across models and ensuring strong metadata governance.

Processing pipelines are executed on Amazon EMR Serverless, with orchestration managed by Apache Airflow operators running on Amazon Managed Workflows for Apache Airflow (MWAA). This provides elastic, cost-efficient compute for both batch processing and fast-time scoring, while keeping orchestration, monitoring, and recovery centralized.

For graph enrichment, the platform connects to Neo4j using a dedicated driver, enabling advanced network-based features like suspicious claim linkages, provider fraud ratios, and centrality metrics.

This architecture supports efficient, reliable, and transparent production execution. It uses repeatable Airflow orchestration, environment-based continuous integration and continuous delivery (CI/CD) promotion, centralized monitoring, failure notifications, retry mechanisms, dead-letter queue handling for Guidewire integration, and controlled secret management. At the same time, the layered lakehouse design keeps the platform flexible enough to evolve with new business needs and fraud detection use cases.

Fraud detection architecture on AWS showing data ingestion to Amazon S3, the Silver, Gold, and Platinum Iceberg layers, Neo4j graph enrichment, Amazon EMR Serverless processing, and Guidewire integration

The data sources here are policy, claims, vehicles, and notes (from AS400 and Guidewire), which are structured data. Derived features that capture entity relationships make up the graph data.

Let’s go through the architecture overview:

  1. Data ingestion – Claim batch data is uploaded to Amazon S3. The data is standardized and materialized in Iceberg tables within the Silver layer.
  2. Graph enrichment – Data processed to update Neo4j graph database hosted on AWS.
  3. Model training and scoring – Batch scoring for several ML models.
  4. Model orchestration – Unified orchestration for ingestion, training, and inference using Apache Airflow operators. CI/CD pipelines for promotion across environments.
  5. Execution platform – Amazon EMR Serverless for cost-efficient Spark processing. Migration to Apache Iceberg plus AWS Glue Data Catalog for scalable metadata handling.
  6. Integration with claims systems – Fraud predictions automatically create Guidewire activities, enriched with a description for investigators.
  7. Secrets and security – AWS Secrets Manager securely stores credentials and tokens for Guidewire API integration, with environment-specific and region-specific access controls.
  8. Monitoring and reliability – Amazon CloudWatch and Amazon Simple Notification Service (Amazon SNS) provide visibility into pipeline health and notify teams on failures. Data quality checks are executed at key stages of the pipeline to validate data availability, schema consistency, completeness, and business-rule expectations before outputs are consumed by models or sent to Guidewire.

Guidewire integration with MLOps on AWS

One of the most important parts of MAPFRE’s solution was closing the loop between ML predictions and the claims handling system. This required a resilient integration between the Atenea data platform on AWS and Guidewire Claims.

Integration flow:

  1. When an ML use case finishes scoring, the results are written as JSON files into the S3 path: <bucket_name>/guidewire/.
  2. An S3 event notification triggers the AWS Lambda function LambdaXXXInvokeGuidewireAPI.
  3. This Lambda function:
    • Reads the JSON file.
    • Calls the Guidewire Predictive Model API.
    • Because Guidewire doesn’t support batch requests, the Lambda function sends each JSON payload individually. This keeps the integration compatible with Guidewire and isolates failures at the individual activity level, but it increases the number of API calls and makes retry, throttling, DLQ handling, and monitoring controls important.
  4. If successful, the API responds with HTTP 201 (activity created).
    • If not, the Lambda retries up to two times.
    • Failed requests are sent to an SQS Dead-Letter Queue (DLQ) and an SNS notification is published to an SNS queue for monitoring.
  5. Secrets are stored in AWS Secrets Manager and injected as Lambda environment variables, along with AWS Region-specific URLs for token retrieval and API endpoints.
  6. Example JSON structure for Guidewire integration:
    {
      "method": "createPredictiveActivity",
      "params": [
        {
          "claimNumber": "AUXXXXXXX",
          "exposureNumber": 1,
          "subject": "Fraud alert from ML model",
          "description": "Claim flagged as potential fraud based on graph + ML features",
          "shortSubject": "ML_Fraud_Flag",
          "priority": "high",
          "availableForClosedClaim": true,
          "autoCloseOnExposureClosure": false,
          "targetDays": 4,
          "escalationDays": 6
        }
      ]
    }

Guidewire integration flow from Amazon S3 to an AWS Lambda function that calls the Guidewire API, with an SQS dead-letter queue and Amazon SNS for failures

Key benefits of this integration:

  • Real-time actionability – Fraud predictions automatically create Guidewire activities for front-line adjusters.
  • Resilience – Built-in retries, DLQ handling, and SNS alerts keep failed events from being lost.
  • Security – Secrets and tokens are managed using AWS Secrets Manager, with strict environment separation (dev, pre, pro).
  • Scalability – Any new MLOps use case writes results into the S3 output path, automatically flowing into Guidewire.

This integration shows that fraud models don’t just exist in isolation but actively augment daily claim workflows in production. It connects Atenea’s MLOps pipelines on AWS directly with business decisioning systems, which is critical to realizing the fraud savings impact.

Data quality and resilience

For robustness, we apply data quality checks on ingestion pipelines and graph features. Automated validation detects anomalies early, monitoring dashboards track KPIs and model performance, and standardized recovery and promotion processes run across environments.

Visualization and investigative tools

Neo4j Bloom supports Special Investigations Unit (SIU) workflows by visually exploring entity relationships, such as a provider linked across multiple suspicious claims, accelerating fraud ring identification.

Neo4j Bloom graph visualization showing a provider node linked across multiple suspicious insurance claims

Conclusion

The fraud detection model for auto claims has enhanced MAPFRE USA’s ability to identify fraudulent activity, driving significant savings and improving overall claims efficiency.

During the pilot phase alone, savings exceeded projections by over half a million dollars, and in production the initiative has proven an NPV of more than $5M at current business volumes. These results confirm the business case and highlight the strength of combining structured data with graph-based features to uncover fraud networks that traditional approaches miss.

The results have been compelling:

  • Accuracy gains – detection improved by 50–135 percent compared to baseline methods.
  • Realized value – In 2025, MA Auto and MA Home claim savings reached a combined total of $6.81M, with $6.59M from MA Auto and $225K from MA Home.
  • Proven return on investment (ROI) – the project delivered an NPV of $4.7M at approval, and results are already exceeding expectations.
  • Cross-functional success – the initiative brought together Claims, IT Data, Advanced Analytics, and Neo4j teams in an agile, collaborative model.

Beyond the financial outcomes, several lessons emerged. First, cross-functional collaboration between groups like Claims, Data Engineering, Advanced Analytics, and technology partners like AWS and Neo4j was critical to success. Second, explainability proved essential. By presenting adjusters with the top model drivers directly in Guidewire, we increased trust and adoption of the system substantially. Finally, building resilience into the architecture through monitoring, retries, and data quality processes helped the models operate reliably in production.

Looking ahead, the platform is well-positioned to expand beyond fraud detection. New use cases such as underwriting anomaly detection, customer entity resolution, and retention modeling are already on the roadmap. With a robust architecture built on AWS using Amazon EMR Serverless, Apache Iceberg on Amazon S3 supported by AWS Glue Data Catalog and AWS Lake Formation, a custom-built Feature Store, and Neo4j, MAPFRE now has a scalable foundation to continue driving innovation and business impact.

To start building a similar solution, open the Amazon EMR console and review the AWS Architecture Center for reference patterns you can adapt to your own fraud detection and analytics workloads.


About the authors

Amazon Redshift delivers faster performance for BI dashboards and real-time analytics

Post Syndicated from Stefan Gromoll original https://aws.amazon.com/blogs/big-data/amazon-redshift-delivers-faster-performance-for-bi-dashboards-and-real-time-analytics/

Business intelligence (BI) dashboards and real-time analytics have become essential tools for making informed decisions quickly. Modern data warehouses must excel at complex, long-running analytical queries and also deliver sub-second response times for the short, ad hoc queries that power interactive and real-time experiences. This matters even more as agents explore and derive new insights from massive amounts of data. From executives monitoring key performance indicators on their morning dashboards to data analysts using agents to explore datasets interactively, the expectation is clear: queries should return results fast and predictably.

Amazon Redshift has long been optimized for these use cases. Over the years, we’ve introduced numerous features designed to improve query performance for BI and real-time analytics workloads, including result caching, materialized views, and automatic workload management (AutoWLM). These capabilities have helped thousands of customers build responsive dashboards and real-time applications on Amazon Redshift. However, we know that when it comes to interactive analytics, every millisecond matters. That’s why we keep focusing on making dashboards load faster and helping exploratory queries return results more quickly.

Today, we’re excited to announce a new performance optimization in Amazon Redshift that improves the response times of low-latency SQL queries, such as those used in real-time analytics applications or generated by BI dashboards. With this enhancement, you can experience improved query latencies because of a reduction in the time Amazon Redshift spends preparing SQL queries for execution. SQL queries start faster, so they return results quicker.

How the optimization works

To understand this improvement, let’s first examine one of Amazon Redshift’s existing core performance capabilities: code generation. Code generation is an optimization technique that analyzes each SQL query and generates query-specific C++ code internally. This code is then compiled and executed in parallel across the available Amazon Redshift compute nodes to deliver results back to you. Code generation has been fundamental to Amazon Redshift query performance, executing complex analytical queries with high efficiency.

While code generation results in performant query execution, new queries can experience a one-time compilation overhead the first time they run. Amazon Redshift already caches compiled code, and more than 99% of queries in the Amazon Redshift fleet execute using this cached generated code and experience no compilation overhead. For queries that haven’t been cached yet, the one-time compilation overhead is most noticeable for fast-running queries (for example, millisecond or single-digit second queries), where it can represent a significant portion of total execution time.

With the optimization we announced, Amazon Redshift reduces this compilation overhead. Here’s how it works: when Amazon Redshift receives a query, it first checks if optimized compiled C++ code already exists in the cache from previous executions of similar queries in the Amazon Redshift fleet. If so, it uses that code for best performance. If not, Amazon Redshift now applies a new query compilation optimization that processes new queries immediately using composition. Composition is a technique that generates a lightweight arrangement of pre-existing logic. At the same time, it creates query-specific optimized code that is compiled and executed across available compute resources to boost performance further. Composition removes compilation from the critical path of query execution and provides immediate execution while compilation proceeds in the background. With this optimization, new queries processed by Amazon Redshift start faster and deliver performance consistent with subsequent runs.

This approach ensures that first-time queries start much quicker, while repeated queries continue to benefit from the same leading price-performance that Amazon Redshift code generation delivers.

The best part? No action is necessary for your queries to start benefiting from this performance optimization. This enhancement is now the default for all SQL queries in Amazon Redshift for all users on provisioned clusters or serverless workgroups in all AWS Regions where Amazon Redshift is available at no additional cost.

Real-world performance results

We analyzed the impact of this new optimization on Amazon Redshift customer clusters. To do so, we measured the compilation time of the 1% of query segments that didn’t get a cache hit in our compilation cache and therefore required compilation. The following chart shows the results. The P50 compilation time before the optimization was 4.3 seconds. With this optimization, the compilation time dropped 25.7x to 170 ms.

Bar chart comparing P50 compilation time on Amazon Redshift before and after the FastCompile optimization, showing a reduction from 4.3 seconds to 170 milliseconds, a 25.7x improvement

With this optimization, BI dashboards load faster, interactive exploration feels more responsive, and real-time analytics applications can deliver insights with lower latency.

What customers are saying

“Following the significant performance improvements that Amazon Redshift demonstrated for cold query execution on our cluster with the FastCompile query performance feature enabled, achieving 2.4x faster query performance with compilation time reduced from 12 seconds to 5 seconds, we have adopted Amazon Redshift as our analytics solution”

— Vijay Hiremath, Group Manager, Business Platforms, Intuit

“As a data platform leader at a leading Chinese liquor company, we rely heavily on Amazon Redshift as our enterprise data warehouse. With diverse analytical query patterns, we faced performance challenges during initial compilation. After testing Redshift’s new cold query compilation enhancement, cold queries now perform nearly as fast as warm queries, with significantly improved speed on diverse queries”

— Yujie Wang, Data Platform Leader, JNC

“In a mid size customer processing about 85 GB of data daily through complex ETL pipelines — multiple tables, mixed DML operations, all landing into our 1.7 TB Amazon Redshift data warehouse, fast compile enhancements accelerated our post-maintenance ETL pipelines by 25%. Now the customer data loads complete faster, data hits analysts sooner for quick decisions”

— Jagan Mohan, Product Engineering Head, Algonomy

Industry-leading price-performance for all of your workloads

To illustrate the impact of this optimization, we simulated a short-running BI-like low-latency workload using a benchmark derived from the industry-standard TPC-DS benchmark. We ran the workload at a relatively small scale of 100 GB on a 3-node RG xlarge Amazon Redshift cluster. At this cluster size and scale, queries finish in milliseconds or single-digit seconds, representing the expected latencies of a typical BI dashboard. The derived TPC-DS benchmark includes 99 different queries that represent a mix of realistic business intelligence workloads, including reporting queries, ad hoc analysis, and data exploration patterns. For this test, we compared a single cold run of these queries on an Amazon Redshift RG cluster with the same run on comparable alternative cloud data warehouses. We launched the warehouses, loaded the data, executed a single run of 99 queries, and measured the total runtime and geometric mean of the queries. No other cluster warm-up or setup was done. This query performance improvement is hardware agnostic. It works on all supported Amazon Redshift hardware instance types, on RA3 and RG on provisioned clusters, and on the hardware that supports serverless workgroups.

The results are shown in table below and summarized in subsequent chart. With this new optimization, Amazon Redshift delivers the fastest runtime and geomean for these short queries at the lowest cost, with up to 8.3x better price-performance than the leading alternative data warehouses for new queries.

. Cost / hr Runtime (sec) Geomean (sec) Runtime comparison Geomean comparison Geomean price-performance
Redshift 3-node RG.xlarge $2.28 235 1.7 baseline baseline baseline
Alternative Warehouse A $3.00 327 2.3 1.4x slower 1.3x slower 1.7x more expensive
Alternative Warehouse B $4.00 538 3.4 2.3x slower 2x slower 3.4x more expensive
Alternative Warehouse C $6.00 907 5.5 3.9x slower 3.2x slower 8.3x more expensive

Bar chart comparing TPC-DS benchmark price-performance for the Amazon Redshift 3-node RG.xlarge baseline against three alternative cloud data warehouses, showing Amazon Redshift fastest at lowest cost and up to 8.3x better price-performance

Conclusion

The new query startup optimization in Amazon Redshift continues our commitment to fast performance across analytical workloads. By reducing compilation overhead, we’ve made BI dashboards and real-time analytics applications more responsive, while maintaining the query execution performance that Amazon Redshift is known for.

Because this optimization is automatically enabled for all Amazon Redshift customers, you can start experiencing these benefits immediately. No configuration changes or query rewrites are required. Your existing queries will run faster.

To learn more, visit Amazon Redshift. To get started, you can try Amazon Redshift Serverless and start querying data in minutes without setting up or managing data warehouse infrastructure. For more details on performance best practices, see the Amazon Redshift Database Developer Guide.

Find the best price performance for your workloads

The benchmark used in this post is derived from the industry-standard TPC-DS benchmark, and has the following characteristics:

  • The schema and data come from TPC-DS unmodified.
  • The queries are used unmodified from TPC-DS. TPC-approved query variants are used for a warehouse if the warehouse does not support the SQL dialect of the default TPC-DS query.
  • The test includes only the 99 TPC-DS SELECT queries. It does not include maintenance and throughput steps.
  • A single power run was run with query parameters generated using the default random seed of the TPC-DS kit. The total runtime and geomean of that single cold run were used for the results in this post.
  • Price performance is calculated as the geomean in seconds divided by 3,600 seconds per hour, multiplied by the cost of the warehouse per hour. The result is equivalent to the geomean cost per query. Published on-demand pricing is used for all data warehouses.

We call this benchmark the Cloud Data Warehouse Benchmark, and you can reproduce the preceding benchmark results using the scripts, queries, and data available on GitHub. It is derived from the TPC-DS benchmark and is not comparable to published TPC-DS results, because our test results do not comply with the specification.

Each workload has unique characteristics. If you’re starting out, a proof of concept is the best way to understand how Amazon Redshift performs for your requirements. When running your own proof of concept, focus on proper cluster sizing and the right metrics: query throughput (the number of queries per hour) and price performance. You can make a data-driven decision by requesting assistance with a proof of concept or by working with a system integration and consulting partner.

To stay current with the latest developments in Amazon Redshift, subscribe to the What’s New in Amazon Redshift RSS feed.


About the authors

Stefan Gromoll

Stefan Gromoll

Stefan is a Principal Engineer with Amazon Redshift where he is responsible for Redshift performance across the stack. In his spare time, he enjoys cooking, playing with his three boys, and chopping firewood.

Ravi Animi

Ravi Animi

Ravi is a Senior Product Management leader in the Redshift Team and manages several functional areas of the Amazon Redshift cloud data warehouse service including performance across the stack, query processing, materialized views, spatial analytics, streaming analytics and migration strategies. He has deep experience with relational databases, multi-dimensional databases, IoT technologies, storage and compute infrastructure services and as a startup founder using AI/deep learning, computer vision, and robotics. He has dual bachelors degrees in physics and electrical engineering from Washington Univ. St. Louis, a masters degree in engineering from Stanford and an MBA from Chicago Booth.

Venkat Govindaraju

Venkat Govindaraju

Venkat is a Principal Engineer in the Amazon Redshift engineering team. He has designed and developed several major features in Amazon Redshift including the feature discussed in this blog. He holds a Ph.D in computer science from the University of Wisconsin, Madison.

Kiran Chinta

Kiran Chinta

Kiran is a Senior Development Manager in the Amazon Redshift engineering team. He has led the delivery of several key features in Amazon Redshift. He has extensive experience leading software engineering teams at Amazon Web Services, IBM and other companies.

Implement multi-tenant search with Amazon OpenSearch Serverless next generation

Post Syndicated from Jon Handler original https://aws.amazon.com/blogs/big-data/implement-multi-tenant-search-with-amazon-opensearch-serverless-next-generation/

Learn how to implement cost-effective multi-tenant search using Amazon OpenSearch Serverless next-generation architecture with scale-to-zero compute and simplified routing through per-account, regional endpoints.

Building multi-tenant search architectures requires balancing data isolation with operational cost and complexity. In this post, we provide code examples for an implementation of multi-tenant search using a collection-per-tenant model with Amazon OpenSearch Serverless per-account, regional endpoints. Collection-per-tenant provides data and workload isolation. The regional endpoint simplifies routing requests for indexing and searching data.

Amazon OpenSearch Serverless is a serverless deployment option for Amazon OpenSearch Service that simplifies infrastructure management, index tuning, and data lifecycle management. OpenSearch Serverless automatically provisions and scales resources to provide consistently fast data ingestion rates and millisecond query response times during changing usage patterns and application demand.

The multi-tenant search problem

In search workloads, a tenant is a logical unit of data and the queries against that data. An eCommerce site has product categories. Each category is a tenant. A blog-hosting platform has blogs. Each blog is a tenant. Tenants map to resources in different ways. In the siloed model, each tenant gets its own container: a domain, collection, or index. In the pooled model, tenants share a container. The hybrid model silos large tenants and pools smaller ones together. Regardless of model, you need a mapping between tenant identifiers and the containers that hold their data, so your application routes requests correctly.

OpenSearch Serverless classic offered a collection-per-tenant strategy that simplified, but did not remove, the need for maintaining a tenant-container mapping. In addition, the cost structure of maintaining collection-per-tenant in classic was not ideal. Classic shared hardware across collections with the same AWS Key Management Service (AWS KMS) key. Tenants with different keys could not share hardware. The cost of the solution was the minimum monthly collection cost multiplied by the tenant count. Building for hundreds or thousands of tenants was cost-prohibitive. Collection groups improved this by allowing hardware sharing across AWS KMS keys, but compute costs were still driven by your indexed data, even during idle periods.

With the next-generation architecture, collection groups scale compute to zero. You pay for compute only when a tenant is actively indexing or searching (storage charges still apply). The addition of the regional endpoint further simplifies multi-tenant workloads by routing traffic to any collection through a single hostname. Together, scale-to-zero compute and the regional endpoint make the collection-per-tenant model both economically viable and operationally straightforward.

The OpenSearch Serverless per-account endpoint

OpenSearch Serverless next generation introduces a per-account, regional endpoint that serves all collections through a single hostname:

https://<account-id>.aoss.<region>.on.aws

The x-amz-aoss-collection-name or x-amz-aoss-collection-id header identifies the target collection on each request. This means one connection pool, one TLS session, and one endpoint to manage regardless of how many collections you have.

From a client perspective, you create a single OpenSearch client pointed at the regional endpoint and route requests by setting a header:

def get_opensearch_client(account_id: str, region: str) -> OpenSearch:
    """Create an OpenSearch client using the regional endpoint."""
    host = f"{account_id}.aoss.{region}.on.aws"
    auth = get_aws4auth(region)

    return OpenSearch(
        hosts=[{"host": host, "port": 443}],
        http_auth=auth,
        use_ssl=True,
        verify_certs=True,
        connection_class=RequestsHttpConnection,
        timeout=60,
    )

Every subsequent request includes the routing header to target a specific collection:

headers = {"x-amz-aoss-collection-name": collection_name}

This is a significant improvement over the classic architecture, where each collection had its own endpoint and you needed to manage separate connections for each.

Collection per tenant with query routing

The architecture is straightforward: one collection group holds all tenant collections, and the regional endpoint handles routing.

Create a collection group with scale-to-zero

client.create_collection_group(
    name="amazon-pqa-cg",
    generation="NEXTGEN",
    standbyReplicas="ENABLED",
    capacityLimits={
        "minIndexingCapacityInOCU": 0,
        "maxIndexingCapacityInOCU": 8,
        "minSearchCapacityInOCU": 0,
        "maxSearchCapacityInOCU": 8,
    },
)

When you set minIndexingCapacityInOCU and minSearchCapacityInOCU to 0, OpenSearch Serverless scales down your compute to 0 OpenSearch Compute Units (OCUs) when they are idle for 10 minutes. You pay only for the storage for your indices. If you want to maintain compute and avoid cold starts, set minIndexingCapacityInOCU or minSearchCapacityInOCU to a value greater than 0.

Create one collection per tenant

Each product category maps to its own collection within the group:

client.create_collection(
    name=name,
    type="SEARCH",
    collectionGroupName=COLLECTION_GROUP_NAME,
)

When choosing a collection name for your tenants, consider privacy, name length, and future ease of upgrading your application. You can use a hash function to map tenant identifiers to collection names.

import hashlib

def collection_name_for_tenant(tenant_id: str) -> str:
    """Generate an opaque collection name from a tenant identifier."""
    return hashlib.sha256(tenant_id.encode()).hexdigest()[:16]

Collection names are visible in API calls and logs. If your tenant ID contains personally identifiable information (PII), that information is also visible in logs. Hashing the tenant ID obfuscates the sensitive information.

OpenSearch Serverless has a 64-character limit on collection names. Your tenant ID can be longer than that. Hashing helps stay within this limit.

You might also want to add a prefix to collection names so that you can use wildcard patterns in access policies. For example, naming collections pqa-a1b2c3d4 lets you write a single data access policy matching collection/pqa-*. Including a version component in the name (such as pqa-v2-a1b2c3d4) makes it straightforward to create new collections during schema migrations without disrupting existing tenants.

Index data using the regional endpoint

A single OpenSearch client handles all collections. The x-amz-aoss-collection-name header routes each request to the correct collection:

headers = {"x-amz-aoss-collection-name": collection_name}

# Build bulk request
action = {"index": {"_index": index_name, "_id": doc["question_id"]}}
batch.append(json.dumps(action))
batch.append(json.dumps(doc))

# Send bulk request routed to the target collection
body = "\n".join(batch) + "\n"
resp = os_client.bulk(body=body, headers=headers)

Query a specific tenant’s data

Searching works the same way. Set the header to target the tenant’s collection:

os_client = get_opensearch_client(account_id, region)
headers = {"x-amz-aoss-collection-name": collection_name}

query = {
    "size": 3,
    "query": {
        "match": {
            "question_text": "4k resolution hdmi"
        }
    },
}

resp = os_client.search(index="questions", body=query, headers=headers)

The application layer maps a tenant ID (in this case, a product category) to a collection name, and the regional endpoint handles the rest. No connection pool management, no endpoint lookups, no per-tenant client instances.

Limitations

There are practical constraints to consider when adopting this pattern.

Cold start latency. When a collection group has scaled to zero compute, the first request takes approximately 10 seconds while capacity provisions. For latency-sensitive tenants, you can send a lightweight warmup query (such as a match_all with size=1) before production traffic arrives.

Collection group limits. There are account-level limits on the number of collections and collection groups. Check the Amazon OpenSearch Serverless quotas for current numbers if you are planning thousands of tenants.

Security policy size. Encryption, network, and data access policies list collection resource patterns. Because tenant count grows, these policy documents grow linearly. Use wildcard patterns to stay within OpenSearch Serverless policy size limits.

No cross-collection queries. Each search request targets exactly one collection. If you need to query across tenants for analytics or global search, you need an aggregation layer or a separate shared collection.

Conclusion

In this post, we showed how the next-generation OpenSearch Serverless architecture makes the collection-per-tenant model practical for multi-tenant search. Scale-to-zero reduces the minimum cost for inactive tenants, fitting the compute resources to the demands of tenants. The regional endpoint eliminates the operational complexity of managing per-tenant connections. You get full data isolation between tenants, independent scaling for each tenant’s workload, and a single endpoint to manage in your application code.

For more information, see the Amazon OpenSearch Serverless documentation.


About the author

Jon Handler

Jon Handler

Jon is a Senior Principal Solutions Architect for Search Services at Amazon Web Services. Jon works closely with OpenSearch and Amazon OpenSearch Service, providing help and guidance to a broad range of customers who have search and log analytics workloads. Prior to joining AWS, Jon’s career as a software developer included four years of coding a large-scale, eCommerce search engine.

Multi-Region identity-based access to Amazon Redshift and S3 Tables

Post Syndicated from Maneesh Sharma original https://aws.amazon.com/blogs/big-data/multi-region-identity-based-access-to-amazon-redshift-and-s3-tables/

Organizations with lines of business operating across multiple AWS Regions increasingly run analytics workloads on globally distributed data. These organizations want to manage users and groups centrally, typically in the AWS Organizations management account and in a single Region, while still letting each line of business access data from the Region where its workloads run. Organizations should govern access based on the actual workforce user and their group memberships in the corporate directory.

With multi-Region support for AWS IAM Identity Center, organizations can federate workforce identities into a single organization instance in their primary Region. After you replicate this instance to additional Regions, member accounts running services such as Amazon Redshift or Amazon Athena in those Regions can integrate with IAM Identity Center locally, to resolve the same centrally managed users and groups.

This solution uses Trusted Identity Propagation (TIP), a capability that passes a user’s Identity Center identity and group memberships through a chain of AWS services. With TIP, when a user authenticates through Identity Center, that identity context flows to downstream services like AWS Lake Formation and Amazon S3 Access Grants. With this approach, you get consistent, identity-based access control without additional AWS Identity and Access Management (IAM) role configurations.

In Part 1 of this series, we showed how to simplify enterprise data access using the Amazon Redshift integration with Amazon S3 Access Grants. We demonstrated how to grant Amazon Simple Storage Service (Amazon S3) permissions to AWS IAM Identity Center users and groups using S3 Access Grants, and tested the integration using a federated user to unload and load data between Amazon Redshift and Amazon S3 within a single AWS Region.

In this post, we extend that solution across AWS Regions. We introduce a fictional company, AnyCompany Global, to illustrate how organizations with global operations can use AWS IAM Identity Center Multi-Region to set up consistent, identity-based access to Amazon Redshift and Amazon S3 Tables across Regions.

Specifically, we demonstrate:

  • How IAM Identity Center Multi-Region replicates identity data so that the same users and groups are available in each enabled Region.
  • How AWS Lake Formation grants fine-grained table-level and column-level access to S3 Tables based on group membership.
  • How S3 Access Grants controls UNLOAD/COPY operations to Amazon S3 based on the same identity.

We also show how to connect with your preferred SQL client.

Fictional scenario: AnyCompany Global

AnyCompany Global is a retail analytics company with a centralized IT team and distributed analytics teams. They use the following personas:

  • Alice — IT administrator (manages IAM Identity Center and AWS accounts).
  • Bob — platform engineer (sets up data infrastructure in us-west-2).
  • Ethan — data analyst (member of the awssso-sales group, queries data).

AnyCompany Global has two AWS accounts:

  • Account A (us-east-1) — management account with IAM Identity Center.
  • Account B (us-west-2) — analytics account with Amazon Redshift, Amazon S3, and the AWS Glue Data Catalog.

The same IAM Identity Center user (Ethan) authenticates once and accesses data in Account B (us-west-2) using the same credentials and group memberships — you don’t need additional user provisioning because IAM Identity Center replicates identities to the secondary Region.

Solution overview

The following diagram illustrates the multi-account, multi-Region architecture. Account A (us-east-1) hosts IAM Identity Center, which replicates identities to us-west-2 where Account B runs the analytics workloads.

Multi-account, multi-Region architecture diagram showing IAM Identity Center in us-east-1 replicating to us-west-2, where Amazon Redshift queries S3 Tables through Lake Formation and writes to Amazon S3 through S3 Access Grants

Figure 1: Multi-account, multi-Region architecture with S3 Access Grants, AWS Lake Formation, and IAM Identity Center.

This solution demonstrates two complementary data access patterns, both controlled by the end user identity:

Pattern Access method Permission controlled by
Pattern A SELECT on S3 table bucket through Amazon Redshift Spectrum Lake Formation
Pattern B UNLOAD/COPY to and from Amazon S3 S3 Access Grants

The solution workflow includes the following steps:

  • Ethan connects from Amazon Redshift Query Editor v2 in us-west-2 and authenticates via the IAM Identity Center endpoint (replicated to us-west-2) using his corporate IdP credentials.
  • For Pattern A (SELECT): Amazon Redshift queries the Amazon S3 Tables catalog (s3tablescatalog). Lake Formation evaluates Ethan’s IAM Identity Center group membership and grants access to the cataloged data.
  • For Pattern B (UNLOAD/COPY): Amazon Redshift requests temporary credentials from S3 Access Grants in us-west-2. S3 Access Grants evaluates the request, matches Ethan’s identity and group membership, and vends scoped temporary credentials for the authorized S3 location.
  • Ethan runs SELECT to query data through Lake Formation, and UNLOAD to write data to Amazon S3 through S3 Access Grants. You don’t need an IAM role ARN in the commands.

Walkthrough

The following sections walk you through enabling IAM Identity Center Multi-Region, configuring Amazon S3 Tables with Lake Formation in the secondary Region, testing both access patterns, and verifying the result with AWS CloudTrail. Start with the prerequisites, then complete each step in order.

Prerequisites

You should have the following prerequisites already set up:

  • AWS Organizations enabled with at least two AWS accounts – Centralized Account(Region 1) and Member Account(Region2)
  • IAM Identity Center enabled in the management account (Account A, us-east-1) with a delegated administration account
  • Corporate IdP integrated with IAM Identity Center (users and groups synced, for example, awssso-sales and awssso-finance groups).
  • Resource sharing enabled in your organization with AWS Resource Access Manager (AWS RAM)
  • Complete solution from Part 1 replicated in us-west-2 (Account B), including:
    • Amazon Redshift cluster (in us-west-2) with IAM Identity Center integration enabled (using the replicated Identity Center endpoint in us-west-2).
    • S3 Access Grants instance configured with IAM Identity Center association
    • Amazon S3 bucket (for example, amzn-s3-demo-bucket-west) with folders for each group (for example, awssso-sales/, awssso-finance/).
    • IAM role for S3 Access Grants (for example, iamidcs3accessgrant) with trust policy and permissions policy.
    • S3 Access Grants location registered and grant created for the awssso-sales group.
    • S3 Access Grants enabled on the Amazon Redshift managed application under Trusted identity propagation
    • Cross-account resource sharing via AWS RAM (if Amazon Redshift and S3 Access Grants are in different accounts)
    • Lake Formation enabled on the Amazon Redshift managed application under Trusted identity propagation
    • Lake Formation and Glue permissions added to the IAM role used in the Amazon Redshift managed application (for example, IAMIDCRedshiftRole). For the required permissions, see Querying data through AWS Lake Formation.
  • An AWS account with an IAM role that has administrative access (e.g., Admin role) configured as a Data Lake Admin in Lake Formation

Note: Creating and using AWS resources in this tutorial incurs charges, including AWS Key Management Service (AWS KMS) keys, S3 table buckets, Amazon Redshift clusters, and Amazon S3 storage. See the cleanup section at the end of this post to avoid ongoing charges.

Step 1: Set up IAM Identity Center Multi-Region

Alice performs this step in the management account (Account A, us-east-1). IAM Identity Center uses encryption at rest for identity data. To enable multi-Region, you must first create a multi-Region customer-managed AWS Key Management Service (AWS KMS) key and replicate it to the additional Region.

Create a multi-Region AWS KMS key

  1. On the AWS KMS console in us-east-1, choose Create key.
  2. For Key type, select Symmetric.
  3. For Key usage, select Encrypt and decrypt.
  4. Under Advanced options, select Multi-Region key.
  5. Provide an alias (for example, idc-multi-region-key).
  6. Apply the AWS KMS key policy as documented in Baseline KMS key policy.

Replicate the key to us-west-2

  1. On the AWS KMS console in us-east-1, select the key you created.
  2. Choose the Regionality tab.
  3. Choose Create new replica keys.
  4. Select US West (Oregon) us-west-2.
  5. Choose Replicate key.

For detailed instructions, see Creating multi-Region replica keys.

AWS KMS console Regionality tab showing the multi-Region replica key configured for an additional Region

Figure 2: Replica key configured for the additional Region.

Add us-west-2 to IAM Identity Center

  1. On the IAM Identity Center console in us-east-1, in the navigation pane, choose Settings.
  2. Choose Add Region.
  3. From the Region list, select US West (Oregon) us-west-2. The list shows Regions where you replicated the customer-managed AWS KMS key.
  4. Choose Add Region.

A blue banner indicates that Identity Center is replicating your workforce identities, configuration, and metadata to the new Region. After the initial replication, the Replication Status column changes to Replicated. Your Identity Center endpoints in us-west-2 are now active.

For detailed instructions, see Add the Region in IAM Identity Center.

IAM Identity Center Settings page with the multi-Region replica key added for us-west-2 and replication status set to Replicated

Figure 3: IAM Identity Center settings showing the multi-Region replica key added for us-west-2.

Update your IdP configuration for the additional Region

You’ve successfully replicated your Identity Center instance to the Oregon (us-west-2) Region. Your workforce identities are now available in that additional Region and can use the new AWS access portal endpoint.

To make sure AWS managed application (service provider-initiated) authentication redirect user to respective application, add the ACS URL for the additional Region so that the app contains both Regional ACS URLs.

In the following section highlighted in red, you can view all ACS URL information:

IAM Identity Center settings page with the View ACS URLs section highlighted in red

Figure 4: IAM Identity Center settings showing the View ACS URLs option.

Copy the respective ACS URL as shown in the following figure:

IAM Identity Center settings page listing the ACS URLs for both Regions

Figure 5: IAM Identity Center settings showing the ACS URLs for both Regions.

Use the following instructions to add the ACS URL for the additional Region in your Identity Center application in Okta:

  1. Log in to the Okta portal as an Admin.
  2. Expand the Applications drop-down in the left pane, then choose Applications
  3. Choose your Identity Center Application
  4. Select the Sign-on tab and choose Edit in the Settings windows.
  5. In the AWS SSO ACS URL1 box under Advanced Sign-on Settings – add the additional ACS URL
  6. Choose Save.

Okta application Sign-on tab with the AWS SSO ACS URL1 box configured for the IAM Identity Center application

Figure 6: Okta application for IAM Identity Center Sign-on tab to add ACS URLs.

Create a permission set for the secondary Region

Create a permission set in the management account to grant federated users console access to Amazon Redshift Query Editor V2 in the secondary Region (us-west-2). For more information about permission sets, see Permission sets.

  1. In the management account, open the IAM Identity Center console.
  2. In the navigation pane, under Multi-Account permissions, choose Permission sets → Create permission set.
  3. Choose Custom permission set, then choose Next.
  4. Under AWS managed policies, select AmazonRedshiftQueryEditorV2ReadSharing.
  5. Under Inline policy, add the following policy:
    {
      "Version": "2012-10-17",
      "Statement": [
        {
          "Effect": "Allow",
          "Action": [
            "redshift:DescribeQev2IdcApplications",
            "redshift-serverless:ListNamespaces",
            "redshift-serverless:ListWorkgroups",
            "redshift-serverless:GetWorkgroup"
          ],
          "Resource": "*"
        }
      ]
    }

  6. Choose Next. Enter a permission set name (for example, Redshift-QEV2-West).
  7. Under Relay state, set the default to the Query Editor V2 URL for the secondary Region: https://us-west-2.console.aws.amazon.com/sqlworkbench/home.
  8. Choose Next, then Create.

After creation, assign this permission set to the relevant IAM Identity Center group (for example, awssso-sales) for Account B (us-west-2).

Step 2: Set up Amazon S3 Tables integration with AWS Glue Data Catalog and Lake Formation in Account B (us-west-2)

In this step, the data lake administrator (Bob) sets up Amazon S3 Tables with Lake Formation for fine-grained access control. He completes the following tasks:

  1. Create an S3 tables bucket.
  2. Enable S3 Tables integration with AWS Glue Data Catalog and Lake Formation.
  3. Register the table bucket with Lake Formation (removes default IAM-based access).
  4. Grant Lake Formation permissions to an IAM Identity Center group (awssso-sales) so that only authorized users can query data through Trusted Identity Propagation.

Step 2.1: Remove default Lake Formation permissions

Before creating S3 Tables resources, disable the default IAMAllowedPrincipals grants that Lake Formation applies to new databases and tables. By default, Lake Formation grants IAMAllowedPrincipals access to new resources, which means that standard IAM policies (rather than Lake Formation permissions) control access. For identity-based access through Trusted Identity Propagation, you need Lake Formation to be the sole arbiter of access.

The order matters. If you remove these defaults before registering the S3 Tables resource, Lake Formation will not apply IAMAllowedPrincipals to your S3 Tables catalog or its children. If you register the resource first, you need to manually revoke the IAMAllowedPrincipals grants from each resource.

From the console

  1. Open the Lake Formation console in your target Region (for example, us-west-2).
  2. In the left navigation, choose Administration → Data Catalog settings.
  3. Uncheck both options:
    • Use only IAM access control for new databases
    • Use only IAM access control for new tables in new databases
  4. Choose Save.

Lake Formation Data Catalog settings page with both default IAM access control options cleared

Figure 7: Lake Formation Data Catalog settings with default IAM access control disabled.

Optional: Verify Lake Formation default permissions through the AWS CLI

aws lakeformation get-data-lake-settings --region <REGION>

Confirm both CreateDatabaseDefaultPermissions and CreateTableDefaultPermissions are empty arrays ([]).

Add AWSServiceRoleForRedshift as a read-only admin

If you plan to query S3 Tables from Amazon Redshift Query Editor V2, you must add the Amazon Redshift service-linked role as a Read-Only Admin in Lake Formation. Complete the following steps:

  • In the Lake Formation console, go to Administration → Administrative roles and tasks.
  • Under Data lake administrators, choose Add. Choose Read only administrator.
  • From the menu, choose AWSServiceRoleForRedshift.
  • Choose Confirm.

Important: Without this, Amazon Redshift Query Editor V2 doesn’t display external databases from s3tablescatalog. The Amazon Redshift service-linked role needs read-only admin access to browse the Data Catalog on behalf of users.

Step 2.2: Create the Lake Formation data access role for S3 Tables

Create an IAM role that Lake Formation assumes to generate temporary, scoped credentials on behalf of users requesting access to S3 Tables data. Lake Formation uses this role (instead of its service-linked role) because Trusted Identity Propagation requires sts:SetContext in the trust policy, which is not available on the service-linked role. Without a custom role with this permission, Lake Formation cannot propagate the user’s IAM Identity Center identity when accessing S3 Tables.

Create the role with the trust policy

aws iam create-role \
    --role-name LFAccessRole-S3Tables \
    --assume-role-policy-document '{
        "Version": "2012-10-17",
        "Statement": [{
            "Effect": "Allow",
            "Principal": {
                "Service": "lakeformation.amazonaws.com"
            },
            "Action": [
                "sts:AssumeRole",
                "sts:SetSourceIdentity",
                "sts:SetContext"
            ]
        }]
    }'

Attach the S3 Tables permissions policy

aws iam put-role-policy \
    --role-name LFAccessRole-S3Tables \
    --policy-name S3TablesDataAccess \
    --policy-document '{
        "Version": "2012-10-17",
        "Statement": [
            {
                "Sid": "LakeFormationPermissionsForS3ListTableBucket",
                "Effect": "Allow",
                "Action": ["s3tables:ListTableBuckets"],
                "Resource": ["*"]
            },
            {
                "Sid": "LakeFormationDataAccessPermissionsForS3TableBucket",
                "Effect": "Allow",
                "Action": [
                    "s3tables:CreateTableBucket",
                    "s3tables:GetTableBucket",
                    "s3tables:CreateNamespace",
                    "s3tables:GetNamespace",
                    "s3tables:ListNamespaces",
                    "s3tables:DeleteNamespace",
                    "s3tables:DeleteTableBucket",
                    "s3tables:CreateTable",
                    "s3tables:DeleteTable",
                    "s3tables:GetTable",
                    "s3tables:ListTables",
                    "s3tables:RenameTable",
                    "s3tables:UpdateTableMetadataLocation",
                    "s3tables:GetTableMetadataLocation",
                    "s3tables:GetTableData",
                    "s3tables:PutTableData"
                ],
                "Resource": ["arn:aws:s3tables:<REGION>:<ACCOUNT_ID>:bucket/*"]
            }
        ]
    }'

Step 2.3: Register S3 Tables with Lake Formation

Register the S3 Tables resource with Lake Formation using the data access role. This step lets Lake Formation manage access to S3 Tables through the Data Catalog and creates the s3tablescatalog federated catalog automatically.

Open the Lake Formation console and complete the following steps:

  1. Choose Catalogs in the navigation pane and choose Enable S3 Table integration.

Lake Formation Catalogs page with the Enable S3 Table integration option highlighted

Figure 8: Lake Formation Catalogs page with the Enable S3 Table integration option.

  1. Select the IAM role and select Allow external engines to access data in Amazon S3 locations with full table access. Choose Enable.

Enable S3 Table integration dialog with the IAM role selected and the Allow external engines option enabled

Figure 9: Enable S3 Table integration dialog with the IAM role and external-engine access configured.

Alternative: Register through the AWS CLI

aws lakeformation register-resource \
    --resource-arn "arn:aws:s3tables:<REGION>:<ACCOUNT_ID>:bucket/*" \
    --role-arn "arn:aws:iam::<ACCOUNT_ID>:role/LFAccessRole-S3Tables" \
    --with-federation \
    --region <REGION>

Important: Verify that the --role-arn matches the exact ARN of the role created in Step 2.2 (including the path). A mismatch (e.g., role/service-role/LFAccessRole-S3Tables vs role/LFAccessRole-S3Tables) will cause credential vending failures later.

Optional: Verify the registration

aws lakeformation list-resources --region <REGION>

Confirm the S3 Tables entry shows WithFederation: true and the correct role ARN.

Step 2.4: Create the S3 table bucket and namespace

Create an S3 table bucket and a namespace. Complete the following steps on the Amazon S3 console:

  1. In the navigation pane, choose Table buckets.
  2. Choose Create table bucket.
  3. On the next page, enter the bucket name as <TABLE_BUCKET_NAME>.
  4. Keep the other options as default and choose Create table bucket.
  5. After you create it, the AWS Management Console redirects you to the list of table buckets. Choose the table bucket <TABLE_BUCKET_NAME>.
  6. Choose Create table with Athena.
  7. Create a namespace in S3 Tables (equivalent to a database in AWS Glue Data Catalog). Enter the namespace (database) name as <NAMESPACE_NAME> and choose Create namespace.

You can also perform these steps using the AWS Command Line Interface (AWS CLI). Refer to Creating a table bucket using the AWS CLI for equivalent commands.

Step 2.5: Grant admin role access

After you remove default permissions, you need to give your Admin role explicit Lake Formation permissions to create tables. Because your Admin role is a Data Lake Admin, you can already see s3tablescatalog in the Amazon Athena console, but creating tables requires an explicit grant.

From the console

  • Open the Lake Formation console in your Region.
  • Choose Data permissions → Grant.
  • Under Principals, select IAM users and roles and choose your Admin role.
  • Under LF-Tags or catalog resources, select Named Data Catalog resources.
  • For Catalogs, choose <Account ID>:s3tablescatalog/<Table_Bucket_Name>.
  • For Databases, select your database (for example, customer_ns_db).
  • Select Super for Database permissions and Grantable permissions.
  • Choose Grant.

After this grant, you can create and insert data into tables from the Athena console.

Note: Your Admin role must be a Data Lake Admin (configured in Step 2.1) to browse s3tablescatalog in Athena. You need the explicit database grant for write operations (CREATE TABLE, INSERT).

Step 2.6: Create a table from the Athena console

  1. Open the Amazon Athena console in your Region.
  2. In the Data source menu, select AwsDataCatalog.
  3. For Catalog, choose s3tablescatalog/<Table_Bucket_Name>.
  4. For Database, choose your namespace.
  5. Run a CREATE TABLE statement. For example:
CREATE TABLE <NAMESPACE_NAME>.<TABLE_NAME> (
    customer_id int,
    first_name string,
    last_name string,
    region string,
    membership_tier string
)
TBLPROPERTIES ('table_type' = 'ICEBERG');

INSERT INTO <NAMESPACE_NAME>.<TABLE_NAME> VALUES
  (1, 'Joyce', 'Deaton', 'West', 'Gold'),
  (2, 'Daniel', 'Dow', 'East', 'Silver'),
  (3, 'Marie', 'Lange', 'West', 'Gold'),
  (4, 'Wesley', 'Harris', 'East', 'Bronze'),
  (5, 'Jerry', 'Tracy', 'West', 'Silver');

Step 2.7: Grant permissions to the IAM Identity Center group

Give your IAM Identity Center group access to query tables. This step enables Trusted Identity Propagation (TIP) for this group. When users in the group access data through TIP-integrated services like Amazon Redshift, Lake Formation evaluates their IAM Identity Center group membership and enforces table-level and column-level permissions accordingly.

From the console

Grant DESCRIBE on the database:

  1. Open the Lake Formation console in your Region.
  2. Choose Data permissions → Grant.
  3. Under Principals, select IAM Identity Center and choose your IAM Identity Center group (for example, awssso-sales).
  4. Under LF-Tags or catalog resources, select Named Data Catalog resources.
  5. For Catalogs, choose <Account ID>:s3tablescatalog/<Table_Bucket_Name>.
  6. For Databases, select your database (for example, customer_ns_db).
  7. For Database permissions, select Describe.
  8. Choose Grant.

Grant SELECT and DESCRIBE on tables:

  1. Choose Data permissions → Grant.
  2. Under Principals, select IAM Identity Center and choose your IAM Identity Center group (for example, awssso-sales).
  3. Under LF-Tags or catalog resources, select Named Data Catalog resources.
  4. For Catalogs, choose <Account ID>:s3tablescatalog/<Table_Bucket_Name>.
  5. For Databases, select your database (for example, customer_ns_db).
  6. For Tables, select All tables (or a specific table).
  7. For Table permissions, select Select and Describe.
  8. Choose Grant.

Tip: You can also configure column-level or row-level permissions for fine-grained access control. When granting on a specific table, additional options for Column permissions and Data filters become available.

Step 2.8: Optional: Verify the Lake Formation permissions

Confirm database-level permissions

aws lakeformation list-permissions \
    --resource '{"Database": {"CatalogId": "<ACCOUNT_ID>:s3tablescatalog/<TABLE_BUCKET_NAME>", "Name": "<NAMESPACE_NAME>"}}' \
    --region <REGION>

Confirm table-level permissions

aws lakeformation list-permissions \
    --resource '{"Table": {"CatalogId": "<ACCOUNT_ID>:s3tablescatalog/<TABLE_BUCKET_NAME>", "DatabaseName": "<NAMESPACE_NAME>", "TableWildcard": {}}}' \
    --region <REGION>

You should see:

  • Your Admin role with ALL permissions at the database level.
  • Your IAM Identity Center group with DESCRIBE permissions at the database level.
  • Your IAM Identity Center group with DESCRIBE on ALL_TABLES and SELECT on ALL_TABLES (with ColumnWildcard) at the table level.
  • No IAM_ALLOWED_PRINCIPALS entries.

Step 2.9: Create Amazon Redshift tables and grant permissions

Connect to the Amazon Redshift cluster in us-west-2 as an admin user and create Redshift local tables. Grant permissions on those local resources to IAM Identity Center groups.

Create a schema and table

CREATE SCHEMA IF NOT EXISTS sales_schema;

CREATE TABLE IF NOT EXISTS
sales_schema.store_sales (
  customer_id INTEGER ENCODE az64,
  product VARCHAR(50),
  sales_amount INTEGER ENCODE az64
)
DISTSTYLE AUTO;

-- Insert sample data
INSERT INTO sales_schema.store_sales VALUES
  (1, 'Laptop', 1200),
  (2, 'Phone', 800),
  (3, 'Tablet', 450),
  (4, 'Monitor', 350),
  (5, 'Keyboard', 120);

Grant permissions to the IAM Identity Center group

GRANT USAGE ON SCHEMA sales_schema TO ROLE "awsidc:awssso-sales";
GRANT SELECT, INSERT FOR TABLES IN SCHEMA sales_schema TO ROLE "awsidc:awssso-sales";

-- Grant access to the S3 Tables external database in Redshift (for Lake Formation queries on customer profiles)
GRANT USAGE ON DATABASE "customers3tables@s3tablescatalog" TO ROLE "awsidc:awssso-sales";

Step 3: Test the solution

In the management account, navigate to the IAM Identity Center console and copy the AWS access portal URL (for example, https://d-1234560789.awsapps.com/start) from the dashboard.

  • Log out from the management account and paste the AWS access portal URL in a new browser window.
  • A pop-up redirects you to your IdP login page. Enter Ethan’s IdP credentials.
  • After successful authentication, you’re logged into the AWS console as a federated user. Select the QEV2 permission set for the secondary Region (us-west-2).
  • In Query Editor V2, open the context (right-click) menu on your Amazon Redshift instance, choose Create connection, and for Authentication, select IAM Identity Center.
  • Because your IdP credentials are already cached, the browser reuses them automatically. You’re now connected to Amazon Redshift.

Pattern A: Query the S3 table catalog using Lake Formation permissions

Query the customer profile data through s3tablescatalog. Lake Formation enforces access based on Ethan’s IAM Identity Center group membership:

SELECT *
FROM "customers3tables@s3tablescatalog"."customer_ns_db"."customer_profiles";

Amazon Redshift Query Editor V2 results pane displaying customer profile rows returned from the s3tablescatalog through Lake Formation

Figure 10: Query results from s3tablescatalog returned through Lake Formation in Amazon Redshift Query Editor V2.

This query reads customer profile data from Amazon S3 through Amazon Redshift Spectrum, with Lake Formation controlling who can access which tables and columns.

Pattern B: Unload data to Amazon S3 using S3 Access Grants

Run the UNLOAD command to write data from Amazon Redshift to the S3 bucket:

UNLOAD ('SELECT * FROM "dev"."sales_schema"."store_sales"')
TO 's3://west-idc-amzn-s3-demo-bucket/awssso-sales/';

You don’t need an IAM role ARN in the command. S3 Access Grants handles authorization based on Ethan’s IAM Identity Center identity and group membership, propagated across Regions using IAM Identity Center Multi-Region support.

Verify the data in Amazon S3

On the Amazon S3 console, navigate to s3://west-idc-amzn-s3-demo-bucket/awssso-sales/ and verify that the unloaded data files are present.

Join Lake Formation data with locally loaded Amazon Redshift data

Combine customer profile data (queried via Lake Formation) with sales data (loaded via S3 Access Grants) using the shared customer_id column:

SELECT c.first_name, c.last_name, c.membership_tier,
  s.product, s.sales_amount
FROM "customers3tables@s3tablescatalog"."customer_ns_db"."customer_profiles" c
JOIN  dev.sales_schema.store_sales s ON c.customer_id = s.customer_id
ORDER BY s.sales_amount DESC;

Amazon Redshift Query Editor V2 results joining S3 Tables customer profiles with the local store_sales table

Figure 11: Joined results from S3 Tables and Amazon Redshift local data, ordered by sales amount.

This shows that you can join S3 Tables data with Amazon Redshift using the same IAM Identity Center identity.

Verify access control

To confirm that S3 Access Grants is enforcing access, try accessing a folder Ethan does not have a grant for:

UNLOAD ('SELECT * FROM "dev"."sales_schema"."store_sales"')
TO 's3://west-idc-amzn-s3-demo-bucket/awssso-finance/';

This should return an access denied error, confirming that S3 Access Grants is controlling access based on the user’s identity and group membership.

Step 4: Verify with AWS CloudTrail

You can verify that Amazon Redshift used both S3 Access Grants and Lake Formation for authorization by checking AWS CloudTrail:

  • On the CloudTrail console, choose Event history.
  • Filter by Event source: s3.amazonaws.com. Look for GetDataAccess events (S3 Access Grants).
  • Filter by Event source: lakeformation.amazonaws.com. Look for GetDataAccess events (Lake Formation).

Both event types show Ethan’s IAM Identity Center user identity, confirming trusted identity propagation works end-to-end for both access patterns.

The following table lists related blog posts and integration guides covering additional identity-based access patterns with Amazon Redshift. Although many of these were written for single-Region deployments, you can extend them to multi-Region environments by first enabling IAM Identity Center Multi-Region as described in Step 1 of this post. Use the table to find the guide that matches your identity provider and tooling:

Integration / use case Identity provider What it covers Blog link
Amazon Redshift federated permissions Any Centralize permission management across multiple Amazon Redshift clusters within a Region using IAM Identity Center-linked database roles. Simplify multi-warehouse data governance with Amazon Redshift federated permissions
Amazon Redshift Query Editor V2, DbVisualizer, DBeaver Any Foundational Amazon Redshift and IAM Identity Center setup, role-based access control (RBAC), JDBC single sign-on (SSO) with PKCE. Integrate IdP with Query Editor V2 and SQL client
Amazon Redshift and S3 Access Grants (single Region and cross-account) Any Amazon S3 data access through UNLOAD/LOAD with identity-based permissions. Simplify data access with S3 Access Grants
Amazon SageMaker Unified Studio with Athena and Amazon Redshift Any SQL analytics with Lake Formation governance. Configure SSO with SageMaker Unified Studio
Amazon QuickSight with Lake Formation Any Cross-account Glue Data Catalog, business intelligence dashboards. Cross-account Glue and Lake Formation
Tableau (Desktop, Server, Prep) Okta TTI plus OIDC setup, Tableau OAuth XML configuration. Integrate Tableau with Okta
Tableau (Desktop, Server, Prep) PingFederate TTI plus OIDC setup, JWT access token manager. Integrate Tableau with PingFederate
Tableau (Desktop, Server, Prep) Microsoft Entra ID TTI plus OIDC setup, Entra app registration. Integrate Tableau with Entra ID
ThoughtSpot Okta / Microsoft Entra ID Native OIDC integration, supports both IdPs. Integrate ThoughtSpot

Key considerations

When implementing this multi-Region architecture, keep the following operational and configuration considerations in mind. These reflect common challenges and design decisions encountered during deployment:

  • IAM Identity Center Multi-Region requires a customer-managed multi-Region AWS KMS key replicated to each additional Region before you can add the Region to Identity Center.
  • S3 Access Grants instances are regional. You need a separate instance in each Region where your users access data. A bucket must be in the same Region as the Access Grants instance that manages it.
  • IAM Identity Center Multi-Region provides the same user and group identities across Regions, so you can use the same group IDs in grants across Regions.
  • You must register Lake Formation data locations with a customer-managed role that includes sts:SetContext in its trust policy. For S3 Tables, use aws lakeformation register-resource with the --with-federation flag and the resource ARN format arn:aws:s3tables:<REGION>:<ACCOUNT_ID>:bucket/*. Using the service-linked role causes the error: Cannot vend credentials from service-linked role to Identity Center principal.
  • SELECT and UNLOAD use different permission models. Lake Formation controls query-time access to cataloged data (SELECT through Spectrum). S3 Access Grants controls direct Amazon S3 access (COPY/UNLOAD). Both use the same IAM Identity Center identity.
  • The Amazon Redshift managed application IAM role must include sts:SetContext in its trust policy and have both Lake Formation/Glue and S3 Access Grants permissions.
  • Cross-account setup requires AWS RAM resource sharing for S3 Access Grants and proper IAM Identity Center application configuration in the analytics account.
  • Scoped vs object-level permissions in Amazon Redshift. When granting permissions with GRANT ... FOR TABLES IN SCHEMA, use REVOKE ... FOR TABLES IN SCHEMA to remove them. The REVOKE ... ON ALL TABLES IN SCHEMA syntax only removes object-level permissions, not scoped permissions.
  • The Lake Formation data access role for S3 Tables requires sts:SetContext in its trust policy (for TIP) and s3tables:* permissions on the table bucket resources.
  • AWSServiceRoleForRedshift must be a Read-Only Admin in Lake Formation for Amazon Redshift Query Editor V2 to display external databases from s3tablescatalog.
  • Federated catalog CatalogId format. When using CLI commands for S3 Tables resources in Lake Formation, use the full path format: <ACCOUNT_ID>:s3tablescatalog/<TABLE_BUCKET_NAME>. Using the account ID alone returns empty results.

Clean up

To avoid ongoing charges, clean up the resources created in this post:

  • Delete the S3 table bucket (delete tables → namespaces → bucket using aws s3tables CLI commands).
  • Deregister the S3 Tables resource from Lake Formation (aws lakeformation deregister-resource --resource-arn "arn:aws:s3tables:<REGION>:<ACCOUNT_ID>:bucket/*").
  • Delete s3tablescatalog from Glue (aws glue delete-catalog --catalog-id "s3tablescatalog").
  • Delete the LFAccessRole-S3Tables IAM role and associated policies.
  • Delete the S3 Access Grants instance and grants in us-west-2.
  • Delete the S3 bucket used for UNLOAD/COPY in us-west-2.
  • Delete the iamidcs3accessgrant IAM role and associated policies.
  • Deregister the S3 data location from Lake Formation.
  • Delete the Lake Formation IAM Identity Center integration.
  • Delete the Amazon Redshift cluster in us-west-2 if you created one for testing.
  • Remove us-west-2 from IAM Identity Center Multi-Region (if no longer needed).
  • Schedule deletion of the AWS KMS replica key in us-west-2 (minimum 7-day waiting period).

Conclusion

In this post, we extended the Amazon Redshift and S3 Access Grants integration to a multi-Region setup using IAM Identity Center Multi-Region replication. We demonstrated two complementary data access patterns: SELECT through Lake Formation for fine-grained access control on S3 Tables data, and UNLOAD/COPY through S3 Access Grants for direct Amazon S3 access. Both patterns use the same IAM Identity Center identity for access control. We also showed how to set up a customer-managed multi-Region AWS KMS key, enable IAM Identity Center in an additional Region, configure Amazon S3 Tables with Lake Formation for identity-based access control using Trusted Identity Propagation, and replicate the complete S3 Access Grants setup in a different Region and account.

With this approach, AnyCompany Global’s analysts authenticate once and access data in any enabled Region while Lake Formation and S3 Access Grants enforce per-user, per-group access policies.

For additional guidance, refer to the following resources:


About the authors

Maneesh Sharma

Maneesh Sharma

Maneesh is a Sr. Specialist Solutions Architect in Analytics at AWS, bringing more than 15 years of hands-on experience in designing and implementing large-scale data warehouse and analytics solutions. He collaborates closely with customers to help them build scalable, high-performance analytical data platforms.

Rohit Vashishtha

Rohit Vashishtha

Rohit is a Senior Analytics Specialist Solutions Architect at AWS based in Dallas, Texas. He has two decades of experience architecting, building, leading, and maintaining big data platforms. Rohit helps customers modernize their analytic workloads using the breadth of AWS services and ensures that customers get the best price/performance with utmost security and data governance.

Srividya Parthasarathy

Srividya Parthasarathy

Srividya is a Senior Big Data Architect with Amazon SageMaker Lakehouse. She works with the product team and customers to build robust features and solutions for their analytical data platform. She enjoys building data mesh solutions and sharing them with the community.

Sandeep Adwankar

Sandeep Adwankar

Sandeep is a Senior Product Manager with Amazon SageMaker Lakehouse. Based in the California Bay Area, he works with customers around the globe to translate business and technical requirements into products that help customers improve how they manage, secure, and access data.

Getting your SMS short code production-ready with AWS End User Messaging

Post Syndicated from Harshvardhan Chunawala original https://aws.amazon.com/blogs/messaging-and-targeting/getting-your-sms-short-code-production-ready-with-aws-end-user-messaging/

Getting your Short Message Service (SMS) short code production-ready requires you to configure the Amazon Web Services (AWS) infrastructure that controls how your messages are sent, monitored, and protected. You have provisioned your short code, and it is active on carrier networks. In this post, we walk through that setup using AWS End User Messaging SMS, covering 12 configuration steps from compliance through phased traffic migration. Total estimated time is 2 to 4 hours of configuration plus 1 to 3 business days for limit increase approvals.mess

The guide to SMS short codes with AWS End User Messaging covers the application and registration process up through provisioning. This post picks up from that point and provides an operational readiness walkthrough that takes you from “Active” status to confidently sending your first production message, including a final validation step to confirm readiness.

The following diagram shows the end-to-end message flow and event routing architecture covered in this walkthrough.

End-to-end SMS short code architecture showing message flow from sender through AWS End User Messaging SMS to carriers and recipient handsets, with event routing to Amazon CloudWatch, Amazon Simple Notification Service (Amazon SNS), and Amazon Data Firehose destinations

Prerequisites

You need the following to follow along with this walkthrough:

  1. An AWS account with access to the AWS End User Messaging SMS console.
  2. A short code with Active status in the AWS Management Console (carrier provisioning finished).
  3. Permissions to create AWS Identity and Access Management (IAM) roles, Amazon CloudWatch Log Groups, and Amazon Simple Notification Service (Amazon SNS) topics.
  4. AWS Command Line Interface (AWS CLI) v2 or an AWS SDK installed and configured.
  5. Your approved registration documentation, including the service name, keyword responses, and message templates submitted to carriers.

Step 1: Verify your short code is active and delivering

Navigate to the AWS End User Messaging SMS console, choose Phone numbers, and locate your provisioned short code. Confirm that the status shows Active, then send a test message to a phone number you control using the SendTextMessage API or the console test feature. Verify delivery on your handset.

Carrier-side activation can take up to 24 to 48 hours to fully propagate across all networks after provisioning finishes. If the console shows Active but your test message does not arrive, submit a support case so the team can verify propagation status with the carrier.

You can also verify using the AWS CLI:

aws pinpoint-sms-voice-v2 send-text-message \
    --destination-phone-number "+15555550100" \
    --origination-identity "12345" \
    --message-body "Test message from short code" \
    --message-type TRANSACTIONAL \
    --configuration-set-name "prod-otp-shortcode"
# Replace +15555550100 with your test phone number, 12345 with your short
# code, and prod-otp-shortcode with your configuration set name from Step 3.

Step 2: Configure keywords and verify message compliance

US carriers require every short code to respond to HELP and STOP keywords. You defined these during your registration, and this step confirms they are configured correctly in your account.

In the SMS console, choose Phone numbers, select your short code, and choose the Keywords tab. Verify that STOP returns the opt-out response you submitted during registration, and that HELP returns your support contact response (which must include a phone number or email). Add any custom keywords your use case requires, such as YES for double opt-in confirmation flows. You can manage keywords programmatically using the PutKeyword API.

To add or update a keyword programmatically:

aws pinpoint-sms-voice-v2 put-keyword \
    --origination-identity "12345" \
    --keyword "YES" \
    --keyword-message "You have confirmed your subscription to Acme Health Alerts. Msg&data rates may apply. Reply STOP to opt out." \
    --keyword-action AUTOMATIC_RESPONSE
# Replace 12345 with your short code, YES with your custom keyword, and the
# keyword-message text with your approved response.

To verify your current keyword configuration:

aws pinpoint-sms-voice-v2 describe-keywords \
    --origination-identity "12345"
# Replace 12345 with your short code.

Beyond keyword configuration, carrier compliance does not end at registration approval. The content you send in production must stay aligned with what carriers reviewed and approved. Here is what to keep consistent.

Use the exact brand or program name from your approved registration across all keyword responses, confirmation messages, and outbound templates. If carriers approved your registration under “Acme Health Alerts,” every message your short code sends should reference that name. Mixing variations creates inconsistencies that auditors flag during reviews. For example, do not use the company name in one message and the product name in another.

Your HELP, STOP, and confirmation responses must match the templates submitted during registration. Do not add or remove opt-out language, change frequency disclosures, or alter customer care contact details post-approval without updating the registration through a support case. If your organization operates multiple domains, use the domain documented in the registration. For example, you might have one domain for the application and another for marketing. Carrier reviewers cross-reference message content, opt-in screenshots, and privacy policy URLs with what was submitted.

Humans conduct carrier reviews, and message content that is concise and limited to the essentials is reviewed consistently. All messages must remain under 160 characters.

Step 3: Create a configuration set with event destinations

A configuration set controls where your SMS delivery events are streamed and which event types are captured. Without one, you are limited to the basic events that AWS End User Messaging SMS sends to Amazon EventBridge by default. These default events omit recipient details and full carrier response context.

Create a configuration set with a descriptive name such as prod-otp-shortcode or marketing-sc-us. Then create at least one event destination. The three main options are Amazon CloudWatch Logs (for operational monitoring and alarming), Amazon SNS (for real-time event fanout to downstream systems), and Amazon Data Firehose (for durable archival and analytics).

Amazon Data Firehose typically delivers to an Amazon Simple Storage Service (Amazon S3) bucket, where you can query delivery history using Amazon Athena for compliance audits or delivery pattern analysis.

# Create the configuration set
aws pinpoint-sms-voice-v2 create-configuration-set \
    --configuration-set-name "prod-otp-shortcode"

# Add a CloudWatch Logs event destination
aws pinpoint-sms-voice-v2 create-event-destination \
    --configuration-set-name "prod-otp-shortcode" \
    --event-destination-name "otp-delivery-logs" \
    --matching-event-types TEXT_DELIVERED TEXT_FAILED TEXT_QUEUED TEXT_CARRIER_UNREACHABLE TEXT_TTL_EXPIRED \
    --cloud-watch-logs-destination '{
        "IamRoleArn": "arn:aws:iam::123456789012:role/SMSEventsToCloudWatch",
        "LogGroupArn": "arn:aws:logs:us-east-1:123456789012:log-group:/aws/sms/prod-otp-shortcode"
    }'
# Replace prod-otp-shortcode with your configuration set name, otp-delivery-logs
# with a descriptive destination name, and the ARN values with your IAM role ARN
# (must have logs:PutLogEvents permission) and CloudWatch Log Group ARN.

Important: When sending messages with SendTextMessage, always specify your ConfigurationSetName parameter so events route to the appropriate destination.

Required event types

Event type Description
TEXT_DELIVERED Message successfully delivered to recipient handset.
TEXT_FAILED Message delivery failed.
TEXT_QUEUED Message accepted and queued for delivery.
TEXT_CARRIER_UNREACHABLE Carrier network unreachable.
TEXT_TTL_EXPIRED Message expired before delivery.

For a detailed walkthrough of configuration sets including multi-tenant architectures, see How to send SMS using configuration sets with AWS End User Messaging.
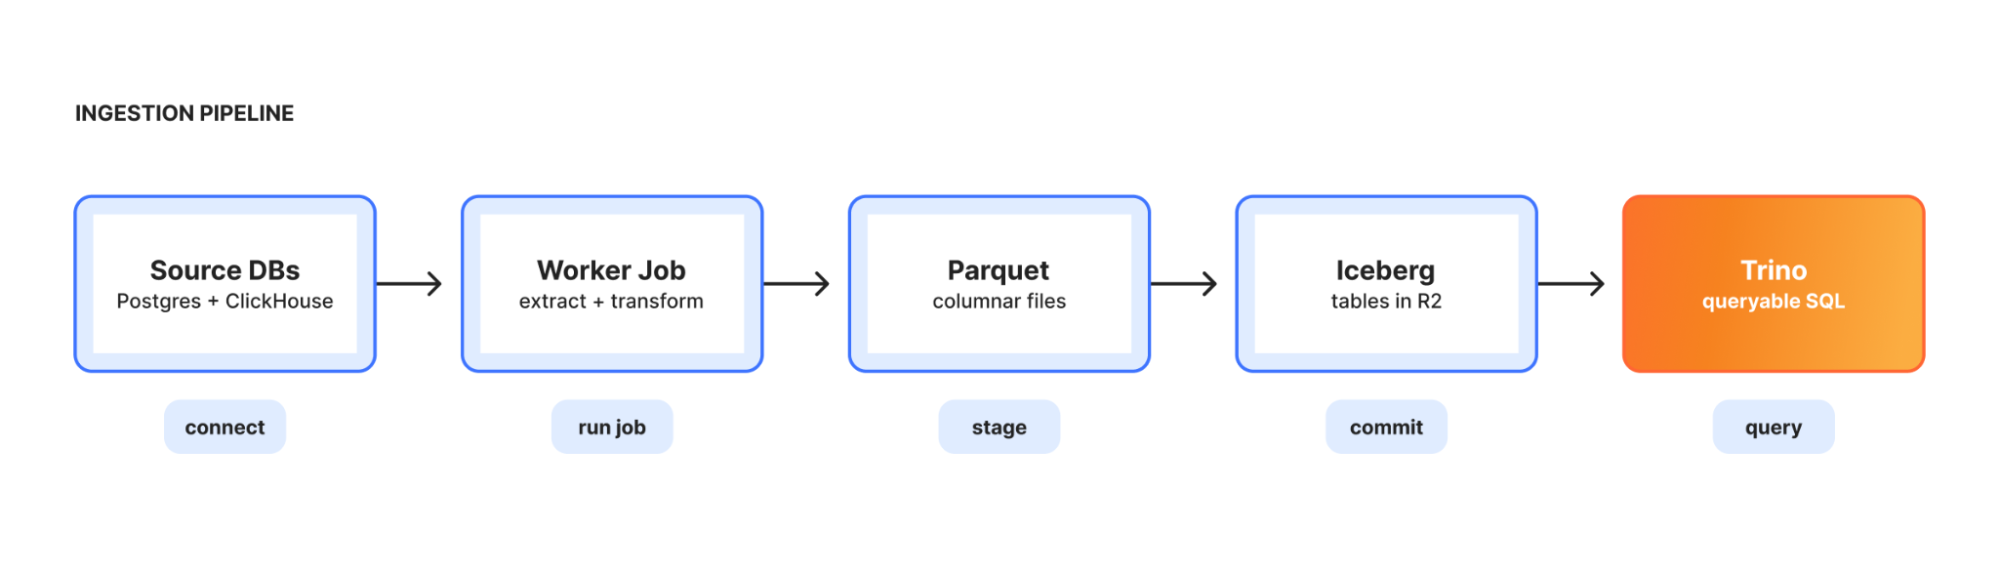
Step 4: Create a phone pool and associate your short code

A pool is a logical container that groups origination identities and controls routing behavior. Creating one gives you deterministic control over which number sends your messages and how opt-outs are enforced.

# Create the pool
aws pinpoint-sms-voice-v2 create-pool \
    --origination-identity "12345" \
    --iso-country-code "US" \
    --message-type TRANSACTIONAL

# Disable shared routes so only your short code is used
aws pinpoint-sms-voice-v2 update-pool \
    --pool-id "pool-1234567890abcdef0" \
    --shared-routes-enabled false
# Replace 12345 with your short code, US with your destination country code,
# and pool-1234567890abcdef0 with the Pool ID returned by create-pool.

Configuration parameters

Parameter Recommended value Rationale
Pool name us-otp-pool Descriptive, environment-prefixed.
SharedRoutesEnabled False Prevents fallback to shared routes; only your short code is used.
Opt-out list Associate one Manages opt-out state per use case.
IsoCountryCode US Restricts to destination country your short code serves.

If you operate multiple use cases on separate short codes, create a dedicated pool for each. For example, use one short code for one-time password (OTP) traffic and another for transactional notifications. This isolation means a recipient opting out of marketing messages does not lose access to authentication codes.

Step 5: Request your throughput increase

Short codes start at a default of 100 messages per second (MPS). If your production volume will exceed this, request an increase before your launch date rather than after traffic is flowing.

Create a case in the AWS Support Center, choose Service limit increase, then choose End User Messaging SMS. Provide your short code phone number, requested MPS, use case description, and expected peak volume. Allow 1 to 3 business days for processing.

To estimate your required MPS:

Required MPS = (Peak hourly volume / 3,600) x 2

Short codes support scaling to thousands of MPS, so start with a value that covers your expected peak and request further increases as traffic grows.

Step 6: Request a spending limit increase

AWS accounts have a default monthly SMS spending limit. To keep delivery uninterrupted at your expected volume, request an increase that accommodates your projected monthly spend before you begin sending.

Create a support case under Service limit increase > End User Messaging SMS > Account Spend Threshold. Provide your estimated monthly spend, use case description, and website URL.

For details, see Requesting increases to your monthly SMS spending quota.

Step 7: Restrict destination countries

If your short code serves a single country (US-only, for example), restrict sending to that country. This protects your account from artificially inflated traffic (SMS pumping). In pumping attacks, messages are routed to international premium-rate numbers, generating significant charges.

In the SMS console, navigate to Account settings, then choose Countries and keep only the countries you intend to send to. The pool-level IsoCountryCode restriction from Step 4 provides an additional enforcement layer at the sending path. Combining account-level country restrictions with pool-level country codes gives you two independent controls that both must be satisfied before a message is sent internationally.

For a detailed walkthrough on SMS fraud prevention controls, see Defending against SMS pumping: new AWS features to help combat artificially inflated traffic.

Step 8: Set up monitoring and alarms

With event destinations configured in Step 3, build proactive alerting that surfaces delivery trends before they affect your end users.

Alarm Metric / Source Threshold
Delivery success rate CloudWatch SMS metrics Alert when below 95%.
Spend threshold CloudWatch billing metric Alert at 80% of monthly limit.
Delivery failures Amazon EventBridge rule on TEXT_FAILED Route to Amazon SNS topic or AWS Lambda.
Carrier unreachable Amazon EventBridge rule on TEXT_CARRIER_UNREACHABLE Route to Amazon SNS topic or AWS Lambda.

Build a CloudWatch dashboard showing messages sent per minute, success versus failure breakdown, and spend accumulation over time.

You can also configure Amazon EventBridge to notify you of registration status changes. AWS End User Messaging SMS publishes events for statuses including REQUIRES_UPDATES, REVIEWING, and PROVISIONING, which is useful if a carrier requests changes during a proactive audit after your short code is already active.

For metric details, see Monitoring SMS activity with Amazon CloudWatch.

Step 9: Track OTP verification success (if applicable)

If your short code delivers OTP or two-factor authentication (2FA) codes, track end-to-end verification success in addition to carrier delivery receipts. A “delivered” status at the carrier level does not confirm the end user received and entered the code.

Tracking verification rates gives you insight into latency patterns when codes expire before arrival, geographic delivery trends, and opportunities to improve conversion. Some use cases involve asynchronous processing where several minutes of computation occur before the SMS is sent. For these, measure the full round-trip from the triggering action to message delivery. This separates application-side latency from carrier-side delivery latency.

For implementation guidance, see Track OTP success with AWS End User Messaging SMS feedback.

Step 10: Set up cost visibility

SMS costs include AWS charges plus per-message carrier surcharges. Setting up cost visibility from day one lets you track spend trends, catch anomalies early, and optimize over time.

Start by activating AWS Cost Explorer and creating a cost allocation tag for your SMS workload. Then configure an AWS Budget with threshold alerts. For example, you might notify at 80% of projected monthly spend. This gives you advance warning of unexpected cost increases, whether from traffic spikes, retry loops, or blocked-country leakage.

Step 11: Plan your traffic migration

A phased rollout validates delivery performance at each stage before you increase volume.

Start with a canary phase (Day 1 to 3) where you route 5 to 10% of traffic to the short code and monitor delivery rates, latency, and event logs. Move to a ramp phase (Day 3 to 7) at 50%, validating throughput and carrier-level delivery across your recipient base. Finish the full migration (Day 7+) at 100%. Decommission your previous origination identity only after confirming stability for at least 48 hours.

Step 12: Validate production readiness and send

Before declaring your short code production-ready, run through the following validation checks:

  1. Confirm your CloudWatch dashboard shows events flowing for TEXT_DELIVERED and TEXT_FAILED (from Step 3).
  2. Send a test message that triggers your STOP keyword. Verify the correct opt-out response is returned and the phone number appears in your opt-out list.
  3. Send a test message that triggers your HELP keyword. Verify the response matches your approved registration.
  4. Check your MPS quota in the support case response (from Step 5). Confirm it matches or exceeds your calculated peak.
  5. Review your country restrictions (from Step 7). Attempt to send a message to a blocked country and confirm it is rejected.
  6. Verify your CloudWatch alarm fires by temporarily lowering the threshold, or by checking that the alarm state is not INSUFFICIENT_DATA.

After all six checks pass, you are ready to begin your phased migration (Step 11) and scale to full production traffic. At this point, your short code is configured, monitored, compliant, and protected.

Automate with a validation script

You can use an AI coding assistant such as Kiro to generate a validation script tailored to your environment. Try a prompt like: “Write a boto3 script that validates my SMS short code is production-ready by checking Active status, HELP/STOP keywords, configuration set existence, and pool association using the pinpoint-sms-voice-v2 client.”

Refine the prompt with specifics from the following reference implementation, such as exact API names, filter parameters, and output format, to match your requirements.

The following script is an example of what that output looks like:

import boto3
import sys

SHORT_CODE = "12345"  # TODO: Replace with your short code (e.g., "67890")
POOL_ID = "pool-1234567890abcdef0"  # TODO: Replace with your pool ID from Step 4
CONFIG_SET_NAME = "prod-otp-shortcode"  # TODO: Replace with your configuration set name from Step 3

client = boto3.client("pinpoint-sms-voice-v2")

# Note: For accounts with many resources, implement NextToken pagination
# on describe_* calls. This script assumes results fit in a single page.


def check_short_code_active():
    """Step 1: Verify short code is Active."""
    response = client.describe_phone_numbers(
        Filters=[
            {"Name": "status", "Values": ["ACTIVE"]},
            {"Name": "number-type", "Values": ["SHORT_CODE"]}
        ]
    )
    numbers = [
        n for n in response["PhoneNumbers"]
        if n["PhoneNumber"] == SHORT_CODE
    ]
    assert len(numbers) > 0, f"Short code {SHORT_CODE} not found or not Active"
    print(f"[PASS] Short code {SHORT_CODE} is Active")


def check_keywords_configured():
    """Step 2: Verify HELP and STOP keywords exist."""
    response = client.describe_keywords(OriginationIdentity=SHORT_CODE)
    keyword_names = [kw["Keyword"].upper() for kw in response["Keywords"]]
    assert "STOP" in keyword_names, "STOP keyword not configured"
    assert "HELP" in keyword_names, "HELP keyword not configured"
    print("[PASS] HELP and STOP keywords configured")


def check_configuration_set():
    """Step 3: Verify configuration set exists."""
    response = client.describe_configuration_sets(
        ConfigurationSetNames=[CONFIG_SET_NAME]
    )
    assert len(response["ConfigurationSets"]) > 0, f"Configuration set {CONFIG_SET_NAME} not found"
    print(f"[PASS] Configuration set '{CONFIG_SET_NAME}' exists")


def check_pool_association():
    """Step 4: Verify pool exists and short code is associated to it."""
    response = client.describe_pools(PoolIds=[POOL_ID])
    assert len(response["Pools"]) > 0, f"Pool {POOL_ID} not found"

    # Verify short code is associated to the pool
    assoc_response = client.list_pool_origination_identities(PoolId=POOL_ID)
    identities = [
        oi["OriginationIdentity"]
        for oi in assoc_response["OriginationIdentities"]
    ]
    assert any(SHORT_CODE in oi for oi in identities), \
        f"Short code {SHORT_CODE} not associated with pool {POOL_ID}"
    print(f"[PASS] Pool '{POOL_ID}' exists and short code is associated")


if __name__ == "__main__":
    checks = [
        check_short_code_active,
        check_keywords_configured,
        check_configuration_set,
        check_pool_association,
    ]
    for check in checks:
        try:
            check()
        except Exception as e:
            print(f"[FAIL] {check.__doc__} - {e}")
            sys.exit(1)
    print("\nAll validation checks passed. Ready for production traffic.")

Cleaning up

If you created test resources while following this walkthrough, you can delete them through the AWS End User Messaging SMS console or with the API to avoid confusion with your production configuration. This includes a test configuration set, test pool, or test event destinations used for validation. Do not delete your production configuration set, pool, or keyword settings.

If you requested a test-level MPS increase or spending limit for validation, update these to your production values through a new support case before going live.

Quick reference checklist

Step Action Key API / Service
1 Verify short code is Active and test delivery SendTextMessage
2 Configure keywords and verify message compliance PutKeyword
3 Create configuration set with event destinations CreateConfigurationSet
4 Create pool and associate short code CreatePool, AssociateOriginationIdentity
5 Request MPS increase for expected throughput AWS Support
6 Request spending limit increase AWS Support
7 Restrict destination countries Console / UpdateAccount
8 Set up CloudWatch alarms and dashboards Amazon CloudWatch
9 Track OTP verification success (if applicable) SMS Feedback events
10 Set up cost visibility AWS Cost Explorer, AWS Budgets
11 Plan phased traffic migration Application-level routing
12 Validate production readiness and send All of the preceding

Conclusion

In this post, we walked through how to configure a newly provisioned SMS short code for production use with AWS End User Messaging SMS. The 12 steps cover keyword verification, message compliance, event monitoring, throughput planning, country restrictions, cost visibility, phased traffic migration, and a final production validation.

You can adapt the sequence to your specific use case and volume profile. For the full registration and application process, see A guide to SMS short codes with AWS End User Messaging. To start configuring, navigate to the AWS End User Messaging SMS console. For the full API reference, see the AWS End User Messaging SMS documentation.


About the author

Beyond JSON blobs: Implementing the VARIANT data type in Apache Iceberg V3

Post Syndicated from Arun Shanmugam original https://aws.amazon.com/blogs/big-data/beyond-json-blobs-implementing-the-variant-data-type-in-apache-iceberg-v3/

Apache Iceberg V3 introduces the VARIANT data type. VARIANT provides data engineers with a high-performance, native solution for managing semi-structured data within the data lake. Consider a massive fleet of IoT sensors: street-level temperature probes, air quality monitors, and vehicle telemetry. Each device emits data in unique JSON structures that constantly evolve with firmware updates.

Historically, engineers were forced to store these payloads as STRING blobs. This legacy approach mandates expensive CPU-intensive parsing at runtime and inflates storage costs with redundant raw text. VARIANT solves these inefficiencies by employing a shredded, binary-encoded format. This allows query engines to skip irrelevant data and access specific nested fields with columnar speed, effectively bridging the gap between the flexibility of JSON and the performance of a structured schema.

VARIANT is stored in Parquet as a three-part group: binary metadata (type and dictionary info), a binary value (the full variant for fallback), and a typed_value group where individual JSON fields are shredded into separate Parquet columns. When you query a specific field, Spark prunes the typed_value group to include only the requested sub-columns. It always retains metadata and the value fallback, so it avoids reading the entire document. This approach delivers two concrete benefits:

  • Reduced query processing time: Queries access only the fields they need without deserializing entire JSON documents. This reduces the amount of data scanned and the time spent on deserialization.
  • Lower storage footprint: Binary encoding compresses more efficiently than raw text, reducing storage costs.

Fields inside the JSON become individually accessible columns under the hood. A query that needs one value out of a deeply nested document no longer must read and deserialize the entire thing. You maintain schema flexibility while gaining the performance characteristics of structured columnar storage.

This post is part 1 of a two-part series. We walk through the basics: creating an Iceberg V3 table with a VARIANT column, inserting semi-structured data, and querying it with variant_get(). In Part 2, we scale to millions of rows and benchmark VARIANT against traditional string storage. We measure the difference in query performance and storage footprint.

Solution overview

This walkthrough demonstrates an end-to-end workflow for working with semi-structured data using the VARIANT data type in Apache Iceberg V3 on Amazon EMR Serverless. Raw JSON payloads are ingested and converted to binary VARIANT format using parse_json(). The data is stored in an Iceberg V3 table where the engine shreds the structure into columnar Parquet sub-columns. You can then query the data efficiently using variant_get() to extract specific fields without deserializing the entire document. AWS Glue Data Catalog manages the table metadata. Amazon Simple Storage Service (Amazon S3) provides the underlying storage.

Note: Check the Apache Iceberg documentation for the latest information on specification status and engine compatibility. Additionally, Fine-Grained Access Control (FGAC) through AWS Lake Formation is not currently supported for the VARIANT data type.

How VARIANT works

When you insert a JSON document into a VARIANT column, Spark converts it from a JSON string into the Variant binary format. During writes, the engine can shred the structure. It extracts individual fields and stores them as native Parquet-typed sub-columns within the VARIANT column’s typed_value group. Fields that are not shredded remain in the binary value column as a fallback. This is conceptually similar to how a columnar table stores each column independently. The difference is that the sub-columns live within a single VARIANT column, and the engine handles the shredding schema automatically.

At query time, when you ask for a specific field using variant_get(), Spark reads only the sub-column that contains that field. It does not need to load or parse the rest of the document. For workloads that repeatedly query a handful of fields out of large, complex JSON payloads, this can significantly reduce the amount of data scanned. It also reduces the time spent deserializing it.

The variant_get() function uses JSON path syntax to navigate the structure. You can extract scalar values with an explicit type (optional), access nested objects, and reach into arrays by index. The function signature is the following.

variant_get(column, '$.path.to.field', 'type')

Where column is the VARIANT column name, the second argument is a JSON path expression, and the optional third argument specifies the expected return type (such as 'string', 'int', or 'double'). When the type argument is omitted, the function returns a VARIANT value that preserves the original encoding.

Running Iceberg V3 on Amazon EMR Serverless

Amazon EMR Serverless 8.0 ships with Apache Spark 4.0.1, which includes native support for Iceberg V3 and the VARIANT data type. You do not need to install additional libraries or configure custom JARs. Amazon EMR Serverless manages the compute infrastructure and scales resources up and down based on workload demand. You can focus on the data rather than the cluster.

While this post uses Amazon EMR Serverless, Iceberg V3 VARIANT support is also available on Amazon EMR on EC2 and Amazon EMR on EKS. You can choose the deployment model that fits your environment.

Getting started

The following walkthrough creates an Iceberg V3 table with a VARIANT column, inserts a set of IoT sensor events, and runs queries to extract fields from the semi-structured payload. Each step includes the code you need to run it on Amazon EMR Serverless.

Prerequisites

Before you begin, verify you have the following:

  • An AWS account with permissions to create Amazon EMR Serverless applications and access Amazon Simple Storage Service (Amazon S3).
  • An Amazon S3 bucket for storing Iceberg table data and scripts.
  • AWS Glue Data Catalog configured for metadata management.
  • An IAM execution role with permissions for Amazon EMR Serverless, Amazon S3, AWS Glue, and Amazon CloudWatch Logs.
  • AWS Command Line Interface (AWS CLI) installed and configured.Note: Running this solution in your AWS account might incur charges for Amazon EMR Serverless, Amazon S3, and AWS Glue. Refer to the respective pricing pages for cost details.

Step 1: Initialize a Spark session with Iceberg V3

Start by creating a Spark session configured to use the Iceberg catalog backed by AWS Glue. The key settings are the Iceberg Spark extensions and the AWS Glue catalog implementation. Replace <YOUR_S3_BUCKET> with your bucket name.

from pyspark.sql import SparkSession
from pyspark.sql.functions import col, parse_json

spark = SparkSession.builder \
    .appName("IcebergV3VariantDemo") \
    .config("spark.sql.extensions",
            "org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions") \
    .config("spark.sql.catalog.glue_catalog",
            "org.apache.iceberg.spark.SparkCatalog") \
    .config("spark.sql.catalog.glue_catalog.warehouse",
            "s3://<YOUR_S3_BUCKET>/warehouse/") \
    .config("spark.sql.catalog.glue_catalog.catalog-impl",
            "org.apache.iceberg.aws.glue.GlueCatalog") \
    .config("spark.sql.catalog.glue_catalog.io-impl",
            "org.apache.iceberg.aws.s3.S3FileIO") \
    .getOrCreate()

When running on Amazon EMR Serverless, some Spark configurations might be set at the application or job level. The configuration shown here is included in the script for completeness. Depending on your Amazon EMR Serverless application settings, you might not need to specify all these properties in the script.

Step 2: Create an Iceberg V3 table with a VARIANT column

Create a namespace and table. The format version must be set to 3 for VARIANT data type support. The following table models IoT sensor events with a few standard columns and a VARIANT column for the semi-structured payload.

spark.sql("CREATE NAMESPACE IF NOT EXISTS glue_catalog.iceberg_v3_demo")

spark.sql("""
CREATE TABLE IF NOT EXISTS glue_catalog.iceberg_v3_demo.sensor_events (
    event_id STRING,
    device_id STRING,
    event_timestamp TIMESTAMP,
    event_data VARIANT
)
USING iceberg
TBLPROPERTIES (
    'format-version' = '3'
)
""")

The event_data column is declared as VARIANT. Iceberg stores it in Parquet as a binary-encoded VARIANT structure (metadata, value, and optional shredded sub-columns) rather than as a plain text string.

Step 3: Insert semi-structured data

To insert JSON data into a VARIANT column, use the parse_json() function. This converts a JSON string into the binary VARIANT format at write time. The following example creates a small DataFrame of IoT events and appends them to the table.

import json
from pyspark.sql.functions import current_timestamp
from pyspark.sql.types import StructType, StructField, StringType

# Sample IoT events with nested JSON payloads
events = [
    ("evt_001", "sensor_001", json.dumps({
        "device": {"manufacturer": "SensorTech", "model": "ST-200",
                   "firmware_version": "3.1.4"},
        "sensors": {"temperature": 22.5, "humidity": 61.3,
                    "air_quality": {"pm25": 12.4, "co2": 415}},
        "network": {"connection": "WiFi", "latency_ms": 42},
        "alerts": [{"severity": "low", "message": "Calibration due"}]
    })),
    ("evt_002", "sensor_002", json.dumps({
        "device": {"manufacturer": "IoTCorp", "model": "IC-500",
                   "firmware_version": "2.8.1"},
        "sensors": {"temperature": 34.1, "humidity": 78.9,
                    "air_quality": {"pm25": 142.7, "co2": 1850}},
        "network": {"connection": "LTE", "latency_ms": 210},
        "alerts": [{"severity": "critical",
                    "message": "Temperature threshold exceeded"},
                   {"severity": "high",
                    "message": "Poor air quality detected"}]
    })),
    ("evt_003", "sensor_003", json.dumps({
        "device": {"manufacturer": "SmartDevices", "model": "SD-100",
                   "firmware_version": "1.5.9"},
        "sensors": {"temperature": 18.7, "humidity": 45.2,
                    "air_quality": {"pm25": 8.1, "co2": 390}},
        "network": {"connection": "Ethernet", "latency_ms": 5},
        "alerts": []
    })),
]

schema = StructType([
    StructField("event_id", StringType(), False),
    StructField("device_id", StringType(), False),
    StructField("event_data", StringType(), False),
])

df = spark.createDataFrame(events, schema)
df = df.withColumn("event_timestamp", current_timestamp())

# Convert JSON string to VARIANT using parse_json
df = df.withColumn("event_data", parse_json(col("event_data")))

df.writeTo("glue_catalog.iceberg_v3_demo.sensor_events").append()
print("Data inserted successfully.")

The parse_json() call is the key step. It takes the raw JSON string and encodes it into the binary VARIANT format before writing to the Iceberg table.

Step 4: Query VARIANT data with variant_get()

Once the data is in the table, you can extract individual fields from the VARIANT column using variant_get(). The following queries demonstrate three common patterns: simple field extraction, deep nested access with filtering, and array element access.

The following queries are shown as raw SQL for readability. To run them in your PySpark script, wrap each query in a spark.sql() call. For example: spark.sql("SELECT ...").show().

Query 1: Simple field extraction

Extract top-level sensor readings from the payload.

SELECT
    event_id,
    device_id,
    variant_get(event_data, '$.sensors.temperature', 'double') AS temperature,
    variant_get(event_data, '$.sensors.humidity', 'double') AS humidity
FROM glue_catalog.iceberg_v3_demo.sensor_events

This query reads only the temperature and humidity sub-columns from the VARIANT data. It does not parse or load the rest of the JSON document.

Query 2: Deep nested access with filtering

Reach into nested objects and filter on a value buried inside the structure.

SELECT
    device_id,
    variant_get(event_data, '$.sensors.air_quality.pm25', 'double') AS pm25,
    variant_get(event_data, '$.sensors.air_quality.co2', 'int') AS co2_level,
    variant_get(event_data, '$.device.manufacturer', 'string') AS manufacturer
FROM glue_catalog.iceberg_v3_demo.sensor_events
WHERE variant_get(event_data, '$.sensors.air_quality.pm25', 'double') > 100.0

The WHERE clause filters directly on a nested VARIANT field. Spark evaluates the predicate against the shredded sub-column without deserializing the full payload.

Query 3: Array element access

Access elements inside a JSON array stored within the VARIANT column.

SELECT
    event_id,
    device_id,
    variant_get(event_data, '$.alerts[0].severity', 'string') AS first_alert_severity,
    variant_get(event_data, '$.alerts[0].message', 'string') AS first_alert_message
FROM glue_catalog.iceberg_v3_demo.sensor_events
WHERE variant_get(event_data, '$.alerts[0].severity', 'string') = 'critical'

Array indexing uses standard bracket notation in the JSON path. This query finds events where the first alert has critical severity and returns the alert details.

Query results showing simple field extraction, nested access with filtering, and array element access from the VARIANT column

Figure 1: Query results showing simple field extraction, nested access with filtering, and array element access from the VARIANT column.

Submitting the job to Amazon EMR Serverless

To run this on Amazon EMR Serverless, save the preceding code as a single PySpark script (for example, iceberg_v3_variant_demo.py), upload it to Amazon S3, and submit it as a job. Replace the placeholder values with your own.

Before submitting the job, make sure you have created an Amazon EMR Serverless application. For instructions, see Getting started with Amazon EMR Serverless in the Amazon EMR documentation.

# Upload script to S3
aws s3 cp iceberg_v3_variant_demo.py \
    s3://<YOUR_S3_BUCKET>/scripts/ \
    --region <REGION>

# Submit the job
aws emr-serverless start-job-run \
    --application-id <APPLICATION_ID> \
    --execution-role-arn arn:aws:iam::<ACCOUNT_ID>:role/EMRServerlessExecutionRole \
    --job-driver '{
        "sparkSubmit": {
            "entryPoint": "s3://<YOUR_S3_BUCKET>/scripts/iceberg_v3_variant_demo.py"
        }
    }' \
    --configuration-overrides '{
        "monitoringConfiguration": {
            "cloudWatchLoggingConfiguration": {
                "enabled": true,
                "logGroupName": "/aws/emr-serverless/applications/<APPLICATION_ID>"
            }
        }
    }' \
    --region <REGION>

Use cases

VARIANT fits naturally into workloads where the data is semi-structured and the schema is not fully known in advance. Some use cases include the following:

  • IoT and sensor data: Device fleets produce telemetry in varying JSON formats that evolve with firmware updates. VARIANT stores these payloads without requiring a fixed schema, and queries can extract specific readings without scanning the entire document.
  • Clickstream analytics: User behavior events on websites and mobile apps carry different attributes depending on the action. Page views, clicks, form submissions, and purchases each have their own structure. VARIANT accommodates these data types in a single column.
  • Log analytics: Application logs, infrastructure metrics, and audit trails often arrive as unstructured or loosely structured JSON. VARIANT lets you ingest them as is and query specific fields on demand, without defining a schema up front.

Clean up

To avoid ongoing charges, delete the resources you created:

  • Drop the Iceberg table and namespace using Spark SQL.
    spark.sql("DROP TABLE IF EXISTS glue_catalog.iceberg_v3_demo.sensor_events")
    spark.sql("DROP NAMESPACE IF EXISTS glue_catalog.iceberg_v3_demo")

  • Stop and delete the Amazon EMR Serverless application.
    aws emr-serverless delete-application --application-id <APPLICATION_ID> --region <REGION>

  • Delete the S3 objects and bucket used for table data, scripts, and logs.
    aws s3 rm s3://<YOUR_S3_BUCKET>/warehouse/ --recursive
    aws s3 rm s3://<YOUR_S3_BUCKET>/scripts/ --recursive

Conclusion

Apache Iceberg V3’s VARIANT type provides an efficient way to store and query semi-structured data in your data lake. Columnar storage and shredding reduce storage costs, and direct field access through variant_get() removes the need to parse JSON strings at query time. On Amazon EMR Serverless, you get this capability without managing infrastructure.

In Part 2 of this series, we scale to millions of rows and benchmark VARIANT against traditional string storage. We measure query performance and storage footprint under realistic workloads.

To learn more about Apache Iceberg on AWS, see Apache Iceberg on AWS prescriptive guidance. For more information about Amazon EMR Serverless, see the Amazon EMR Serverless documentation.


About the authors

Arun Shanmugam

Arun Shanmugam

Arun is a Senior Analytics Solutions Architect at AWS, with a focus on building modern data architecture. He has been successfully delivering scalable data analytics solutions for customers across diverse industries. Outside of work, Arun is an avid outdoor enthusiast who actively engages in CrossFit, road biking, and cricket.

Suthan Phillips

Suthan Phillips

Suthan is a Senior Analytics Architect at AWS, where he helps customers design and optimize scalable, high-performance data solutions that drive business insights. He combines architectural guidance on system design and scalability with best practices to provide efficient, secure implementation across data processing and experience layers. Outside of work, Suthan enjoys swimming, hiking, and exploring the Pacific Northwest.

Ron Ortloff

Ron Ortloff

Ron Ortloff is a Principal Product Manager at AWS, where he focuses on Apache Iceberg, S3 Tables, and open data lakehouse solutions. He has over 15 years of experience building and leading data platform initiatives, including launching Azure Synapse Analytics at Microsoft and leading Iceberg and data lake strategy at Snowflake. When he’s not building data platforms, Ron can be found cheering on his favorite football and hockey teams.

Xiaoxuan Li

Xiaoxuan Li

Xiaoxuan is a Software Development Engineer at AWS, working on the performance and scalability of Apache Iceberg in large-scale data lakehouse systems. Her interests span query optimization, storage-efficient architectures, and distributed data processing. Outside of work, she explores AI systems for creative storytelling and tooling for writers and content creators.

Build stateful streaming applications with Apache Spark 4.0 on Amazon EMR Serverless

Post Syndicated from Raj Ramasubbu original https://aws.amazon.com/blogs/big-data/build-stateful-streaming-applications-with-apache-spark-4-0-on-amazon-emr-serverless/

Apache Spark 4.0 represents a major milestone in stream processing, introducing new capabilities that fundamentally change how developers build stateful streaming applications. At the heart of these improvements is the transformWithState API – a new capability that enables first-class support for timers, automatic state management, and schema evolution to Spark Structured Streaming.

With Spark 4.0 now available on Amazon EMR Serverless, developers can build stateful streaming applications using the transformWithState API in a fully managed, serverless environment that automatically scales based on workload demands. This combination delivers the power of sophisticated stream processing without the operational overhead of cluster management.

In this post, we demonstrate how to build a production-ready IoT device monitoring system using Spark 4.0’s transformWithState API on Amazon EMR Serverless. This example showcases the key capabilities of stateful streaming and provides a template you can adapt for your own use cases.

Apache Spark 4.0: introducing transformWithState

Apache Spark 4.0’s latest streaming features solve common production challenges in stateful applications by introducing native timer support and advance state management capabilities for complex event processing workflows. The new transformWithState API provides:

Key features of transformWithState

  • Native timer support: Register timers that fire callbacks at specific times for use cases like heartbeat monitoring, session timeout detection, and SLA violation alerts.
  • Automatic state TTL (Time-To-Live): Configure automatic expiration policies to prevent state from growing indefinitely. This is useful for use cases like session state size control, clearing stale device telemetry, maintaining a recency cache, or tracking invalid logins within the last hour for fraud detection.
  • Schema evolution: Evolve state schema without restarting from a new checkpoint. Add optional fields, remove fields, or widen numeric types. This is particularly valuable for use cases where data structures are dynamic, and application downtime for schema migration is not acceptable, enabling more resilient and flexible real-time streaming applications.
  • Multiple state variables: Support for multiple independent state variables (ValueState, ListState, MapState) per key, well-suited for building complex, real-time applications that require sophisticated state management, such as storing a history of recent error codes, tracking counts of various alert types, or maintaining multiple dimensions of user activity within a single stateful operator.
  • State observability: Query application state mid-stream using the State Data Source Reader for debugging and monitoring. This is especially valuable in applications that require maintaining and evolving state through several steps, such as detection of sophisticated event patterns across multiple streams and over time, where visibility into state transitions is critical for troubleshooting and validation.
  • Operator chaining: Chain multiple stateful operators together for complex multi-stage processing pipelines.

These capabilities make Spark 4.0 ideal for applications that were previously difficult or impossible to implement efficiently, such as complex event processing, session analytics, anomaly detection, and real-time monitoring systems.

Use case: IoT heartbeat monitoring

Consider a fleet of 100,000 IoT sensors deployed across manufacturing facilities. Each sensor sends a heartbeat signal every 20 seconds to indicate it’s operational. Your operations team needs to be alerted within 30 seconds if any sensor goes offline, with repeat alerts every 60 seconds until the sensor comes back online.

This seemingly simple requirement presents several technical challenges. The application must maintain the last heartbeat timestamp for each of the 100,000 devices while independently managing timers to detect missed signals per device. It also needs to handle out-of-order heartbeats caused by network delays and clean up state for decommissioned devices to prevent unbounded memory growth. All of this must happen at scale, processing millions of events per minute with low latency, while recovering gracefully from failures without losing state.

To address the specific challenges of IoT heartbeat monitoring described above, we present a solution built on the transformWithState API in Spark 4.0. With its native timer support, automatic state management, and built-in fault tolerance, making it the ideal solution for IoT heartbeat monitoring at scale.

Solution overview

Our solution architecture follows a serverless, event-driven design:

Solution architecture showing IoT devices sending heartbeats to Kinesis Data Streams, processed by EMR Serverless with transformWithState, checkpointed to Amazon S3, and alerts delivered via Amazon SNS

  1. IoT devices send heartbeat events to Amazon Kinesis Data Streams containing device ID, timestamp, and metadata (battery level, signal strength, firmware version).
  2. Amazon EMR Serverless reads from Kinesis using the Spark aws-kinesis connector using VPC Endpoint for Kinesis, then parses JSON events into structured DataFrames and grouping by device_id.
  3. transformWithState processes each device’s stream. On heartbeat arrival, it updates state and registers a 30-second timer; when the timer expires without a new heartbeat, it emits an offline alert.
  4. State is automatically persisted to RocksDB locally and checkpointed to Amazon Simple Storage Service (Amazon S3), enabling fault-tolerant recovery and exactly-once processing semantics.
  5. Alerts are delivered via Amazon Simple Notification Service (Amazon SNS) to configured subscribers (email, SMS, AWS Lambda, webhooks).

Prerequisites

Before implementing this solution, verify that you have:

  1. AWS account: With permissions for EMR Serverless, Kinesis, SNS, S3, VPC, and IAM.
  2. AWS Command Line Interface (AWS CLI): Configured with appropriate credentials.
  3. VPC setup: VPC with private subnets and security groups configured.
  4. Kinesis VPC interface endpoint: VPC endpoint for private connectivity to Kinesis.
  5. Kinesis Data Stream: Created for ingesting heartbeat events (for example, iot-heartbeats). For testing your streaming data solution, refer to Test your streaming data solution with the new Amazon Kinesis Data Generator.
  6. SNS topic: Created for sending alerts (for example, iot-alerts).
  7. S3 bucket: For storing application code, dependencies, and checkpoints.

Step-by-step implementation

The following steps walk you through setting up an EMR Serverless application with Spark 4.0, configuring the stateful streaming processor, and deploying the IoT heartbeat monitoring solution.

Step 1: Create the EMR serverless application

Run the following command in your terminal using the AWS CLI. Replace the subnet and security group IDs with the values from your VPC setup.

# Create EMR Serverless application with Spark 4.0 and VPC
aws emr-serverless create-application \
  --name "iot-heartbeat-monitor" \
  --release-label "emr-spark-8.0.0" \
  --type "SPARK" \
  --network-configuration '{
    "subnetIds": ["subnet-xxxxx", "subnet-yyyyy"],
    "securityGroupIds": ["sg-zzzzz"]
  }' \
  --region us-east-1

The command returns a JSON response containing the application details. Note the applicationId value from the output, as you will need it in subsequent steps.

Step 2: Implement the heartbeat monitor

The core of our solution is the HeartbeatMonitor class that extends StatefulProcessor. This class demonstrates the key features of Spark 4.0’s transformWithState API. Download the full implementation script and upload it to your local S3 bucket for execution. Let’s walk through each component to understand how it works.

2.1 Initialize state variables

The init() method is called once when the processor is initialized. This is where we define and register our state variables.

from pyspark.sql.streaming.stateful_processor import (
    StatefulProcessor, StatefulProcessorHandle
)

class HeartbeatMonitor(StatefulProcessor):

    def init(self, handle: StatefulProcessorHandle) -> None:
        self.handle = handle

        # Define state schemas
        last_seen_schema = StructType([
            StructField("timestamp", TimestampType(), True)
        ])

        device_info_schema = StructType([
            StructField("battery_level", StringType(), True),
            StructField("firmware_version", StringType(), True)
        ])

        # Initialize multiple independent state variables
        self.last_seen = handle.getValueState("last_seen", last_seen_schema)
        self.device_info = handle.getValueState(
            "device_info", device_info_schema
        )

In the init() method, we use StatefulProcessorHandle to define and initialize two per-key state variables, last_seen and device_info, using Spark’s StructType schemas and the getValueState() API. These state variables are automatically stored in RocksDB and checkpointed to S3, allowing for fault-tolerant state management across streaming micro-batches.

2.2 Handle incoming heartbeat events and register timers

The handleInputRows() method is called whenever new events arrive for a device. This is where we update state and register timers.

def handleInputRows(
    self, key: tuple, rows: Iterator[pd.DataFrame], timerValues
) -> Iterator[pd.DataFrame]:
    device_id = key[0]

    # Process incoming heartbeats - iterate through all rows to find latest
    latest_timestamp = None
    for pdf in rows:
        for _, row in pdf.iterrows():
            ts = row['timestamp']
            if pd.isna(ts):
                continue
            if latest_timestamp is None or ts > latest_timestamp:
                latest_timestamp = ts

    if latest_timestamp is None:
        yield pd.DataFrame()
        return

    # Check if we have existing state
    existing_timestamp = None
    if self.last_seen.exists():
        existing_state = self.last_seen.get()
        existing_timestamp = existing_state[0]

    # Update state only if new heartbeat is more recent
    if existing_timestamp is None or latest_timestamp > existing_timestamp:
        # Cancel existing timers (device is back online)
        for timer in self.handle.listTimers():
            self.handle.deleteTimer(timer)

        # Update state with new timestamp
        self.last_seen.update((latest_timestamp,))

        # Register timer for heartbeat deadline detection
        current_time_ms = timerValues.getCurrentProcessingTimeInMs()
        deadline_ms = current_time_ms + HEARTBEAT_INTERVAL_MS
        # 30 seconds from now
        self.handle.registerTimer(deadline_ms)

    yield pd.DataFrame()  # No output from input handling

The handleInputRows() method processes incoming heartbeat events for each device by extracting the latest timestamp, updating the last_seen state, and managing timers. It cancels existing ones and registering a new 30-second expiry timer to detect future inactivity. Because alerts are only emitted upon timer expiration, the method yields an empty dataframe during normal heartbeat processing.

2.3 Handle timer expiration and emit alerts

The handleExpiredTimer() method is called when a registered timer fires. This is where we detect offline devices and emit alerts.

def handleExpiredTimer(
    self, key: tuple, timerValues, expiredTimerInfo
) -> Iterator[pd.DataFrame]:
    device_id = key[0]
    current_time_ms = timerValues.getCurrentProcessingTimeInMs()

    # Verify state exists
    if not self.last_seen.exists():
        yield pd.DataFrame()
        return

    # Get last seen timestamp from state
    last_seen_state = self.last_seen.get()
    last_seen_timestamp = last_seen_state[0]

    if last_seen_timestamp is None or pd.isna(last_seen_timestamp):
        yield pd.DataFrame()
        return

    # Calculate how long device has been offline
    last_seen_ms = int(last_seen_timestamp.timestamp() * 1000)
    offline_duration_ms = current_time_ms - last_seen_ms
    offline_duration_seconds = offline_duration_ms / 1000.0

    # Create alert as a Pandas DataFrame
    alert_df = pd.DataFrame({
        "device_id": [device_id],
        "alert_type": ["DEVICE_OFFLINE"],
        "last_seen": [last_seen_timestamp],
        "offline_duration_seconds": [offline_duration_seconds],
        "alert_timestamp": [datetime.fromtimestamp(current_time_ms / 1000.0)]
    })

    # Register another timer for repeat alerts (every 60 seconds)
    next_alert_time = current_time_ms + ALERT_REPEAT_INTERVAL_MS
    self.handle.registerTimer(next_alert_time)

    yield alert_df  # Emit the alert

The handleExpiredTimer() method is triggered automatically when a device’s inactivity timer expires, retrieving the last_seen state to calculate the offline duration and yielding an alert dataframe to the output stream. It also registers a follow-up timer for repeat alerts every 60 seconds, which continues until a new heartbeat arrives and cancels the timer via handleInputRows().

There are several ways you could extend this solution for production use. You could implement exponential backoff for repeat alerts to reduce noise, for example, alerting after 60 seconds, then 2 minutes, then 5 minutes, and so on. Other improvements could include adding severity escalation based on offline duration, integrating with notification services like Amazon SNS for downstream alerting, or setting a maximum retry limit to stop alerts for permanently decommissioned devices.

2.4 Apply transformWithState to the streaming DataFrame

Now we connect everything together by applying our HeartbeatMonitor processor to the streaming data.

# Read and parse heartbeat events from Kinesis
parsed_df = kinesis_df \
    .selectExpr("CAST(data AS STRING) as json_data") \
    .select(from_json(col("json_data"), heartbeat_schema).alias("heartbeat")) \
    .select(
        col("heartbeat.device_id"),
        to_timestamp(col("heartbeat.timestamp")).alias("timestamp"),
        col("heartbeat.battery_level"),
        col("heartbeat.signal_strength"),
        col("heartbeat.firmware_version")
    )

# Apply transformWithState for stateful processing
alerts_df = parsed_df \
    .groupBy("device_id") \
    .transformWithStateInPandas(
        statefulProcessor=HeartbeatMonitor(),
        outputStructType=alert_output_schema,
        outputMode="append",
        timeMode="processingTime"
    )

# Write alerts to SNS
query = alerts_df.writeStream \
    .outputMode("append") \
    .foreachBatch(send_to_sns) \
    .option("checkpointLocation", CHECKPOINT_LOCATION) \
    .trigger(processingTime="10 seconds") \
    .start()

# Send to SNS for alerts
def send_to_sns(batch_df, batch_id):
    if batch_df.count() > 0:
        sns_client = boto3.client('sns', region_name=KINESIS_REGION)
        for row in batch_df.collect():
            message = {
                "device_id": row["device_id"],
                "alert_type": row["alert_type"],
                "last_seen": str(row["last_seen"]),
                "offline_duration_seconds": row["offline_duration_seconds"],
                "alert_timestamp": str(row["alert_timestamp"])
            }
            sns_client.publish(
                TopicArn=SNS_TOPIC_ARN,
                Message=json.dumps(message),
                Subject=f"Device Offline Alert: {row['device_id']}"
            )

The streaming pipeline parses JSON heartbeat events from Kinesis, partitions them by device_id, and applies the HeartbeatMonitor stateful processor using transformWithStateInPandas() with processing-time timers and append output mode. The resulting alert stream is written to SNS via foreachBatch() with checkpointing enabled for fault tolerance and micro-batches triggered every 10 seconds.

To summarize, implementing the heartbeat monitor requires just three methods. The init() method sets up your state variables, handleInputRows() processes incoming heartbeats and manages timers, and handleExpiredTimer() generates offline alerts. The transformWithState API handles the underlying complexity of state management, checkpointing, and timer scheduling automatically.

Step 3: Create IAM role for job execution

Create an IAM role that allows EMR Serverless to assume it for running your Spark job. For detailed instructions on creating an IAM role, see Creating an IAM role. Use the following trust policy for the role.

{
  "Version": "2012-10-17",
  "Statement": [{
    "Effect": "Allow",
    "Principal": {
      "Service": "emr-serverless.amazonaws.com"
    },
    "Action": "sts:AssumeRole"
  }]
}

Attach a permissions policy that grants the role access to read from the Kinesis stream, write to the S3 bucket for checkpoints and application artifacts, and publish alerts to the SNS topic:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "KinesisAccess",
      "Effect": "Allow",
      "Action": [
        "kinesis:GetRecords",
        "kinesis:GetShardIterator",
        "kinesis:DescribeStream",
        "kinesis:DescribeStreamSummary",
        "kinesis:ListShards",
        "kinesis:SubscribeToShard"
      ],
      "Resource": "arn:aws:kinesis:us-east-1:*:stream/iot-heartbeats"
    },
    {
      "Sid": "SNSPublish",
      "Effect": "Allow",
      "Action": "sns:Publish",
      "Resource": "arn:aws:sns:us-east-1:*:iot-alerts"
    },
    {
      "Sid": "S3Access",
      "Effect": "Allow",
      "Action": [
        "s3:GetObject",
        "s3:PutObject",
        "s3:DeleteObject",
        "s3:ListBucket"
      ],
      "Resource": [
        "arn:aws:s3:::your-bucket",
        "arn:aws:s3:::your-bucket/*"
      ]
    }
  ]
}

Step 4: Upload external dependencies required for executing the streaming job

In this step, you will download the required external dependencies and upload them to your S3 bucket to make them available for your EMR Serverless streaming job.

  • Spark-kinesis-connector.jar (download link) and copy to local S3 bucket s3://your-bucket/jars/spark-kinesis-connector.jar.
  • Protobuf Dependency (download link) and copy to local S3 bucket s3://your-bucket/pyfiles/protobuf_pkg.tar.gz.

Step 5: Submit the streaming job

Now that the application, IAM role, and dependencies are in place, you can submit the streaming job. This step configures the Spark job parameters and submits it to your EMR Serverless application in streaming mode. For more details on submitting jobs, see Starting a job run.

First, create a file named job-driver.json with the following content. Replace the S3 paths with the locations where you uploaded your script and dependencies in the previous steps.

{
  "sparkSubmit": {
    "entryPoint": "s3://your-bucket/scripts/heartbeat_monitor.py",
    "sparkSubmitParameters": "--jars s3://your-bucket/jars/spark-kinesis-connector.jar --archives s3://your-bucket/pyfiles/protobuf_pkg.tar.gz#protobuf_pkg --conf spark.executor.cores=4 --conf spark.executor.memory=16g --conf spark.driver.cores=4 --conf spark.driver.memory=16g --conf spark.executor.instances=3 --conf spark.sql.streaming.stateStore.providerClass=org.apache.spark.sql.execution.streaming.state.RocksDBStateStoreProvider --conf spark.sql.streaming.stateStore.rocksdb.changelogCheckpointing.enabled=true --conf spark.emr-serverless.driverEnv.PYTHONPATH=./protobuf_pkg --conf spark.executorEnv.PYTHONPATH=./protobuf_pkg"
  }
}

Then, run the following command to submit the job. Replace the application ID and account ID with your own values.

aws emr-serverless start-job-run \
  --application-id <YOUR_APPLICATION_ID> \
  --execution-role-arn arn:aws:iam::<ACCOUNT_ID>:role/EMRServerlessJobRole \
  --job-driver file://job-driver.json \
  --mode STREAMING \
  --retry-policy maxFailedAttemptsPerHour=1 \
  --region us-east-1

Running transformWithState on Amazon EMR Serverless provides several operational advantages over self-managed Spark clusters. In streaming mode, the Spark driver remains alive between micro-batches, eliminating the overhead of repeatedly starting and stopping the application. You don’t need to provision or manage executors because EMR Serverless automatically scales compute resources up and down based on workload demands, so you only pay for what you use. Your IoT heartbeat monitor can handle traffic spikes, such as thousands of devices reconnecting simultaneously after a network outage, without manual intervention. EMR Serverless also provides built-in job resiliency, real-time monitoring, and enhanced log management, reducing the operational burden of running streaming applications in production.

Testing the solution

Now that our streaming application is deployed, let’s test it by sending heartbeat events and observing the offline detection behavior.

Step 1: Open AWS CloudShell

Open AWS CloudShell in your AWS account from the AWS Management Console.

Step 2: Send heartbeat events using CLI

Execute the following bash script to send heartbeat events every 10s.

#!/bin/bash

while true; do
  aws kinesis put-record \
    --stream-name iot-heartbeats \
    --partition-key device-001 \
    --data $(echo "{\"device_id\":\"device-001\",\"timestamp\":\"$(date -u +%Y-%m-%dT%H:%M:%SZ)\",\"battery_level\":87.5,\"signal_strength\":-42.3,\"firmware_version\":\"v2.1.0\"}" | base64) \
    --region us-east-1

  aws kinesis put-record \
    --stream-name iot-heartbeats \
    --partition-key device-002 \
    --data $(echo "{\"device_id\":\"device-002\",\"timestamp\":\"$(date -u +%Y-%m-%dT%H:%M:%SZ)\",\"battery_level\":87.5,\"signal_strength\":-42.3,\"firmware_version\":\"v2.1.0\"}" | base64) \
    --region us-east-1

  aws kinesis put-record \
    --stream-name iot-heartbeats \
    --partition-key device-003 \
    --data $(echo "{\"device_id\":\"device-003\",\"timestamp\":\"$(date -u +%Y-%m-%dT%H:%M:%SZ)\",\"battery_level\":87.5,\"signal_strength\":-42.3,\"firmware_version\":\"v2.1.0\"}" | base64) \
    --region us-east-1

  sleep 10
done

Update the timestamp field to use the current time for each event or use a script to automate sending events at regular intervals.

Step 3: Observe normal operation

As you send heartbeat events every 10 seconds, the Spark application receives each event and updates the device’s state. A timer is then registered for 30 seconds in the future. Each new heartbeat cancels the existing timer and registers a new one, effectively resetting the countdown. As long as heartbeats continue to arrive within the 30-second window, no alerts are sent.

Timeline diagram showing normal device operation over 60 seconds with heartbeats arriving every 10 seconds, each resetting the 30-second timer

The above timeline diagram shows a 60-second window of normal device operation. Heartbeat events arrive every 10 seconds (at 0s, 10s, 20s, 30s, 40s, 50s, and 60s), each resetting the 30-second timer window. Because every heartbeat arrives well within the 30-second threshold, the timer never expires, the device state remains online, and no alerts are triggered.

Step 4: Test offline detection

Stop sending heartbeat events for the device and wait 30 seconds. You should receive an SNS alert indicating the device is offline.

Timeline diagram showing offline detection over 110 seconds with the 30-second timer expiring and triggering SNS alerts

Timeline diagram showing offline detection over 110 seconds. Device sends heartbeats at 0s, 10s, and 20s before going offline. The 30-second timer expires at 50s triggering Alert #1 via SNS, followed by a repeat Alert #2 at 110s after a 60-second repeat timer.

If you continue to not send heartbeats, additional alerts will be sent every 60 seconds.

Step 5: Test device recovery

Resume sending heartbeat events using the same CLI command. The application will cancel all existing timers for the device and will stop sending SNS alerts.

Timeline diagram showing device recovery lifecycle with timers canceled and device returning to online state

Timeline diagram showing the complete device recovery lifecycle over 140 seconds across three phases: normal operation with heartbeats, offline detection with SNS alerts, and recovery where timers are canceled and the device returns to online state

Clean up

To avoid incurring ongoing charges, follow these steps to clean up the resources.

Step 1: Stop the EMR serverless application

Stop your running streaming job:

aws emr-serverless stop-job-run \
  --application-id <your-application-id> \
  --job-run-id <your-job-run-id>

Step 2: Delete the EMR serverless application

aws emr-serverless delete-application \
  --application-id <your-application-id>

Step 3: Delete kinesis data stream

aws kinesis delete-stream --stream-name iot-heartbeat

Step 4: Remove S3 objects

Delete the checkpoint data, scripts, and dependencies from your S3 bucket:

aws s3 rm s3://your-bucket/checkpoints/ --recursive
aws s3 rm s3://your-bucket/scripts/ --recursive
aws s3 rm s3://your-bucket/jars/ --recursive
aws s3 rm s3://your-bucket/pyfiles/ --recursive

Real-world use cases for stateful streaming

The transformWithState API enables developers to build sophisticated streaming applications that were previously difficult to implement. Here are a few examples of how it can be applied across industries.

Telecommunications and network monitoring: Telecom providers need to detect network anomalies and SLA violations as they happen across millions of concurrent sessions. With transformWithState, developers can maintain per-session state to track call detail records, compare real-time network metrics against established baselines, and trigger alerts the moment thresholds are breached. Automatic state TTL ensures that completed session records are cleaned up without manual intervention.

Financial services and fraud detection: Detecting fraud requires correlating multiple signals across a sequence of transactions in real time. With transformWithState, developers can maintain per-account state that tracks transaction histories, flags suspicious patterns like rapid purchases across geographies, and calculates rolling risk scores. Multiple state variables per key allow tracking different dimensions of activity, such as transaction velocity, location changes, and spending deviations, within a single stateful operator.

E-commerce and customer engagement: Understanding customer behavior in real time is critical for driving conversions. Using transformWithState, developers can build session-aware applications that track browsing and cart activity with timer-based state expiration, detecting cart abandonment after a configurable timeout and triggering personalized re-engagement notifications. The State Data Source Reader enables teams to inspect session state mid-stream, making it easier to debug and validate real-time customer journey logic.

Conclusion

Apache Spark 4.0’s transformWithState API represents a significant advancement in stateful stream processing, making it simpler to build complex real-time applications like IoT device monitoring. Combined with Amazon EMR Serverless, you get a fully managed platform that scales automatically and eliminates infrastructure management overhead.

This post demonstrates how to use the native timer support capability of transformWithState to build a real-time IoT device monitoring application. We encourage you to explore other capabilities such as Automatic State TTL, Schema Evolution, and Multiple State Variables on Amazon EMR Serverless to build more sophisticated streaming applications tailored to your needs.


About the authors

Raj Ramasubbu

Raj Ramasubbu

Raj Ramasubbu is a Senior Specialist Solutions Architect for Analytics and AI at AWS. He partners with ISV customers to design and implement modern data platforms that balance performance, cost efficiency, and operational resilience at scale. With over two decades of experience spanning data engineering, advanced analytics, and machine learning across industries such as healthcare, financial services, and retail, Raj brings a practitioner’s perspective to solving complex data challenges in the cloud.

Rekha Veeraraghavan

Rekha Veeraraghavan

Rekha Veeraraghavan is a Technical Account Manager at Amazon Web Services (AWS). She serves as a Subject Matter Expert in AWS Analytics services, specializing in AWS Glue and Amazon Athena. Rekha provides expert guidance and technical support to enterprise and strategic customers, helping them optimize data analytics solutions. With deep expertise in data engineering, she enables organizations to build scalable, efficient, and cost-effective data processing pipelines on AWS.

Praveen Krishnamoorthy Ravikumar

Praveen Krishnamoorthy Ravikumar

Praveen Krishnamoorthy Ravikumar is an Analytics Specialist Solutions Architect at AWS. He helps customers design and implement modern data and analytics platforms that leverage the scalability, flexibility, and innovation of the cloud. He is passionate about solving complex data challenges and enabling organizations to unlock actionable insights from their data.

Introducing the next generation of Amazon OpenSearch Serverless for building your agentic AI applications

Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/introducing-the-next-generation-of-amazon-opensearch-serverless-for-building-your-agentic-ai-applications/

Today, we’re announcing the next generation of Amazon OpenSearch Serverless, a fully managed search and vector engine designed for customers building AI agents. The next generation of OpenSearch Serverless scales from zero to thousands of requests per second and back to zero when idle, offering up to 60% cost savings compared to the cost of OpenSearch Service clusters provisioned for peak capacity.

The next generation of OpenSearch Serverless creates resources in seconds and scales capacity up to 20 times faster than the previous generation. With instant resource creation and native integrations with AI development platforms like Vercel and Kiro, you can deploy production-ready search and vector backends for your AI agents in minutes without managing infrastructure.

The next generation of OpenSearch Serverless in action
To get started with the next generation of OpenSearch Serverless, choose Create collection in the Serverless menu in the Amazon OpenSearch Service console.

Create NextGen collection with instant auto scaling and scale-to-zero for cost optimization. At launch, we support full-text search and vector search only for the collection type. If you want to use the existing OpenSearch Serverless infrastructure, choose Switch to Classic.

Choose Express create, the fastest way to create collection. No configuration is required—the default settings and matching security policies are applied automatically. Some configuration options can be changed later.

When you choose Create collection, OpenSearch Serverless will provision resources in seconds.

You can also create a collection of OpenSearch Serverless with AWS Command Line Interface (AWS CLI) or AWS SDKs. Here is a sample CLI command to create a collection group.

aws opensearchserverless create-collection-group \
    --name channy-nextgen-group \
    --standby-replicas ENABLED \
    --generation NEXTGEN \
    --description "My NextGen collection group" \
    --capacity-limits '{
        "maxIndexingCapacityInOCU": 10,
        "maxSearchCapacityInOCU": 10,
        "minIndexingCapacityInOCU": 0,
        "minSearchCapacityInOCU": 0
    }' \
    --region "us-east-1"

Now, you can create a collection that inherits the generation from its parent collection group. Supported collection types: SEARCH and VECTORSEARCH.

aws opensearchserverless create-collection \
    --name channy-nextgen-collection \
    --type SEARCH \
    --collection-group-name channy-nextgen-group \
    --standby-replicas ENABLED \
    --description "My collection in NextGen group" \
    --region "us-east-1"

To learn more about managing the next generation of OpenSearch Serverless, visit the Amazon OpenSearch Serverless documentation.

Building your agents faster with OpenSearch Serverless
To support building production-ready agent applications in Vercel, you can now create a new OpenSearch collection or connect your existing OpenSearch Serverless collection within the Vercel console. Create a search backend in seconds and add features on-demand as your application grows. To learn more, visit AWS for Vercel.

You can go from idea to working prototype in minutes using Claude Code, Cursor, and Kiro. OpenSearch Agent Skills provide a repository of skills that bring OpenSearch intelligence directly into your agent. Each skill encapsulates domain knowledge, best practices, and multi-step execution logic for a specific workflow–so your agent not only gets results, but understands how they were achieved. You can also use the OpenSearch Launchpad in Kiro Powers to accelerate search applications with guided, end-to-end architecture planning.

Now available
The next generation of Amazon OpenSearch Serverless is generally available today and is available in all AWS commercial Regions where Amazon OpenSearch Serverless is currently available.

The next generation of OpenSearch Serverless charges for the compute you use in OpenSearch Compute Units (OCUs) for indexing, search, and GPU acceleration. You are charged separately for storage in GB-month. For more information, see Amazon OpenSearch Service Pricing.

Give it a try and send feedback to the AWS re:Post for Amazon OpenSearch Service or through your usual AWS Support contacts.

— Channy

How we built Cloudflare’s data platform and an AI agent on top of it

Post Syndicated from Brian Brunner original https://blog.cloudflare.com/our-unified-data-platform/

Cloudflare processes more than a billion events every second. Our network spans 330+ cities in 120+ countries. Behind every HTTP request, every Worker invocation, every R2 read operation, there is data, and a lot of it.

For years, that data was not very easy to access. It lived in dozens of production databases, ClickHouse clusters, Kafka streams, Google Cloud buckets, BigQuery datasets, and a long tail of pipelines. To answer a simple question like “How many domains that signed up today are in the Top 100 by traffic?”, an analyst at Cloudflare had to know which system to ask, what credentials to use, what query language to write, and whether the data they were looking at was sampled, fresh, or seven-days stale. As a result, it was difficult to glean informed insights from the data.

To solve this problem, we built two in-house tools: Town Lake, Cloudflare’s unified data analytics platform, and Skipper, an AI data agent that runs on top of it. Town Lake is a single SQL interface to everything Cloudflare knows, and Skipper is how anyone at Cloudflare can ask questions in plain English and get correct, auditable answers back in seconds.

This is the story of how we built both.

The shape of the problem

If you have ever worked at a company that went through a hyper-growth period, you know what data sprawl looks like. Ours had a few specific symptoms:

  1. Too many disparate systems. A product engineer who wanted to investigate a customer issue might need to query Postgres for account metadata, ClickHouse for analytics events, BigQuery for usage rollups, R2 for raw logs, and Kafka topics for real-time signals. Each system had its own credentials, its own language, and its own retention policy.

  2. Sampled data. This is fine for dashboards, but doesn’t work for domains like billing. Our analytics pipeline downsamples to handle 700M+ events per second. That is the right behavior when you want an analytics dashboard to load, but it’s exactly the wrong behavior when you are trying to compute someone’s usage required to issue an invoice.

  3. External dependencies for internal data. Parts of our previous internal reporting stack were powered by external vendors. Beyond the cost, we had a hard external dependency on another cloud for some of our critical data.

  4. No one could find the data. Even if you had all the right credentials, you needed to know that the right table for “Billable Workers requests by account” lived in a specific ClickHouse cluster, in a specific schema, joined to a specific Postgres dimension table, and that the join required an obscure customer ID translation. There was too much tribal knowledge.

We had a cultural challenge too: data infrastructure had historically been treated as a back-office function that was in service of the business, rather than critical infrastructure in its own right.

What we wanted

We wanted to create one place where anyone at the company with appropriate permissions and a need to know could get answers to questions about Cloudflare: “Show me the top 100 customers by revenue in the last quarter”, “List all Bot Management ML scoring events with score > 0.9 in the last 48 hours coming from a specific ASN”, “Find the Top 100 billing support tickets from customers who have spent >$100”, etc.

We wanted that place to give fresh, accurate, unsampled data for the queries that need it (like billing or security investigations) and fast, downsampled data for the queries that don’t (like dashboards or exploration).

We wanted security and governance baked in, with personally identifiable information (PII) detected automatically, and sensitive tables locked down by default. All access should be auditable, and have time-bounded permission grants so that users could only access data when they were actively working on tasks that required it.

We wanted it to be built on Cloudflare’s own platform: R2 for storage, Workers for compute, Cloudflare Access for authentication, Workflows for orchestration. If we were going to make a major investment in our data infrastructure, it was going to be built on the same products we sell to customers.

And we wanted, eventually, an interface that did not require knowing any SQL. The goal was to empower anyone at the company with appropriate permissions and a need to know to look at the stream of data flowing through our network, not just analysts.

That last requirement is what became Skipper.

Town Lake, the platform

At its core, our data platform’s architecture is a data lakehouse: a query engine that reads from object storage, with a metadata layer that makes the storage behave like a database. We call it Town Lake, after its namesake in Austin, Texas.

Its most important components are:

Query engine. We chose Apache Trino for that: a single SQL query can join a Postgres table, a ClickHouse table, and an Iceberg table on R2 without a need to materialize the intermediate results into a different system. A query that asks “what are the top 100 paying customers by Workers requests this week” compiles into a plan that pushes filters into ClickHouse, joins against an account dimension in Postgres, and ranks against billing rollups in R2, all in one go.

R2 Data Catalog, our managed Apache Iceberg service, is where the cold and warm data lives. Iceberg gives us schema evolution, time travel, partition evolution, and the ability to compact data as it ages. Per-minute usage from last week becomes hourly, hourly from last quarter becomes daily, etc. The storage cost decreases as recency does, while the data stays queryable. Parquet files in R2 are much cheaper compared to keeping the same data in an OLAP database.

DataHub is our metadata catalog. Every table, column, owner, lineage edge, and glossary term lives there. When a user asks “what’s in townlake.dim.accounts,” DataHub provides an answer, including the table description, the column descriptions, the owning team, the upstream tables that feed it, and the downstream tables that consume it.

Lifeguard is our access control service: it stores access rules in D1, dynamically pulls user and group membership from our internal access management system, and renders a combined JSON policy that Trino reads over HTTP. Lifeguard also feeds basic access information to Skipper and the Gateway, so users get blocked at the front door rather than at query time.

Skimmer is a PII detection scanner. It runs continuously, samples rows from every column in every table, and uses Workers AI to classify whether each column contains PII. It does this in two passes: first, a fast per-column classifier; then, if anything is flagged, an agentic second pass that gets full table context and can query Trino directly to verify. Findings flow into DataHub and into Lifeguard’s allowlist to allow human-in-the-loop review.

Transformer is our ELT (extract, load, transform) engine built on Workflows. Users define a Directed Acyclic Graph (DAG) of SQL transformations with YAML frontmatter (target table, materialization mode, dependencies, schedule). Transformer compiles the graph and runs it on Trino, with state managed by Durable Objects, definitions stored in R2, and run history in D1.

Ingestion is the bridge from operational systems into the lake. An orchestrator runs as a long-lived Kubernetes deployment, reads pipeline configs, and spawns short-lived worker jobs to extract from Postgres or ClickHouse, transform to Parquet, and load into R2 as Iceberg tables. Each pipeline runs as either full-replace or incremental-append.


Default-closed: governance by construction

A real concern when you build a unified data platform is that you have just built a large sensitive-data surface. The traditional answer to this is: open by default, restrict by exception. Allow access to everything, then audit and lock down sensitive tables when someone notices.

Town Lake takes the opposite approach. Tables are inaccessible for querying until they have been reviewed. When a new database is connected to Trino or a new table is created, Skimmer scans it, classifies its columns, and registers it in the central allowlist as pending. Until a reviewer approves the table, and the specific columns within it, users can’t query it. This sounds painful, and it would be, except for two things.

First, it’s automated. Skimmer’s classifier is reasonably good: it catches obvious PII (emails, IPs, names, phone numbers) and the long tail of non-obvious sensitive data (API tokens that match certain prefixes, opaque IDs that can be traced back to users). Reviewers see what was detected and either approve, override, or deny. Most reviews take seconds.

Second, the workflow is self-serve. If you query a table you don’t have access to, the error message is not “permission denied.” It’s “this table needs review, click here to request one.” Skipper, the AI agent, will even suggest the right RBAC group to request and link you straight to it.

We separate schema discovery from data access. Users can see what tables exist, but unreviewed columns are hidden from DESCRIBE and SHOW COLUMNS and from SELECT *. That subtle distinction matters: it means a new unreviewed column doesn’t break existing dashboards built on the rest of an approved table.

PII is opt-in per session. By default, Trino redacts sensitive columns before they ever hit your screen. If you have a legitimate need for raw PII (e.g., fraud investigation), you flip the bit on the session, your permissions are checked, and the redaction is lifted. The flip and every query is logged.

Skipper: the AI data agent

A query engine alone isn’t enough these days. SQL is still a barrier, as is knowing which of tens of thousands of tables to query — you need to know the canonical schema.

Skipper is our take on a conversational AI agent that goes from natural-language question to validated answer, grounded in the company’s actual data, code, and institutional knowledge. We built it on top of Town Lake and on top of our developer platform: Workers, Workers AI, Durable Objects, D1, R2, Workflows, KV.

The interface is a chat box. Ask a question:

Show me the top 10 customers by R2 storage cost in the last 30 days, and the change versus the previous 30 days.

Skipper finds the right tables (DataHub search), pulls their schemas and lineage, writes the SQL, submits it to Trino, polls for results, and shows you a table or a chart. Follow up:

Now break it down by region, and ignore internal Cloudflare accounts.

It carries the context, refines the query, and reruns it. If something looks wrong, e.g., a join produced zero rows or a filter excluded what you expected, then Skipper investigates, adjusts, and tries again, in the closed-loop reasoning. The hard part was having the right context.

Skipper can also package charts into dashboards that can be shared internally and embedded into other internal applications. It also has tools for building transformation graphs via Transformer and for checking access and permissions via Lifeguard.

Skipper meets its users wherever they are. All of these tools are available via a Worker backed by a built-in agentic harness powered by Workers AI. On the flip side, many of our internal users work via local agentic flows, and Skipper’s tools are additionally available via an MCP server.

Layers of context

An LLM, given a SQL prompt and a list of table names, can hallucinate joins, misuse columns, and confidently produce a number that is completely wrong. We learned this the hard way during early experiments. The fix is multiple layers of grounded context that the model can pull from at retrieval time.


Layer 1: Schema and usage metadata. DataHub knows every column, every type, every primary key, every foreign key for every table. It also knows which tables are commonly joined together based on historical query patterns. Skipper’s search_datasets and get_entity_details tools surface this directly.

Layer 2: Human annotations. When the team that owns dim.accounts writes a description like “Account-level entity. One row per account_id. Every account belongs to exactly one customer (via customer_id FK),” that description lives in DataHub and ends up in Skipper’s context. Tags like curated mark validated tables that Skipper should prefer over scratch space.

Layer 3: Code-derived knowledge. Some of the most valuable context is not in any catalog: it’s in the SQL that produces the table. The Transformer pipeline emits per-node .meta.json documentation to DataHub on every successful run. So when Skipper looks at fct.billings_allocated, it doesn’t just see the schema; it sees that this is a pre-joined fact table built from dim.accounts, dim.customers, and seed.product_classification, with its alloc_amount column computed as billed_amount / 12 for annual; billed_amount for monthly. That’s the kind of nuance that separates a correct answer from a confidently wrong one.

Layer 4: Curated data models. We maintain a small set of “data model” pages: short, human-written documents that describe how to think about billing, customers, accounts, and zones. “Prefer tables tagged ‘curated’. Avoid scratch_r2 and tables tagged ‘internal’. Search with data model terms (e.g., ‘billing product revenue’) not natural language.” These are surfaced as MCP resources that the agent can pull when the question matches.

Layer 5: Runtime introspection. When everything else fails, Skipper can issue live queries to Trino: DESCRIBE table, SELECT DISTINCT col LIMIT 20, SELECT COUNT(*). It uses these sparingly as runtime context is expensive, but it’s the safety net that makes the rest of the system robust.

Skipper as MCP: Code Mode

One specific implementation detail is worth pulling out, because it is uniquely a Cloudflare-shaped solution.

When you build an AI agent with tools, the standard pattern is to define the tools in your prompt, let the model call them one at a time, parse the response, execute, and return results. This is fine, but it is chatty: a five-tool workflow is five model round-trips, each of which has to re-establish context.

For our MCP server, we use Code Mode. Instead of defining 30 individual tools, we expose two: search and execute. The model writes a JavaScript snippet that calls our entire toolset programmatically:

const datasets = await skipper.search_datasets({ query: "billing product revenue" })
const queryId = await skipper.start_query({ sql: "SELECT ..." })
const results = await skipper.fetch_results({ queryId, mode: "inject" })
return skipper.create_chart({ chartType: "bar", data: results.rows, ... })

That JavaScript runs in a sandboxed Dynamic Worker isolate via WorkerLoader. The model gets to express complex multi-step workflows in a single round-trip, in a language it already knows extremely well. It’s faster, it’s cheaper, and the workflows it produces are auditable as code.

The security model is the data model

Everything Skipper does runs as the calling user. If you don’t have access to a table, Skipper can’t query it for you. If you ask for PII, your permissions are checked. If a query you save is shared with a teammate, their access is checked at view time, not at save time, because group membership changes.

Shared dashboards have their own twist. They can be embedded in any internal Cloudflare tool with a single placeholder div and a script tag:

<div data-skipper-dashboard="dash-123"></div>
<script src="https://skipper.cloudflare.com/embed.js" async></script>

The iframe auto-resizes to fit content. Content Security Policy (CSP) frame-ancestors blocks embedding from anywhere outside the corporate domain. Cloudflare Access still gates the iframe contents, so an unauthenticated viewer hits the Access login page in the iframe rather than seeing the data. Non-owner viewers are checked against the underlying tables: if they don’t have access, they get pointed at the right group to request.


What it powers: really fast answers

Billing. This was the original use case. Our Billable Usage Dashboard, the customer-facing dashboard that shows pay-as-you-go users exactly what they owe, is powered by a metering pipeline whose source of truth is a set of Iceberg tables in R2, queried via Trino. The dashboard’s API pulls the same compact (date, account_id, metric_name, usage) rows that the invoicing system uses, so the number on the dashboard matches the number on the bill.

Billing-related queries account for 53% of all queries Town Lake serves: 91,760 queries from 324 distinct Cloudflare employees in a recent measurement period. The 200–300 line legacy SQL queries that used to compute revenue rollups by customer are now five lines.

Business intelligence. The “top 100 customers by revenue” question takes about three seconds in Skipper now. So does “how many domains that signed up today are in the top 100.” So do most of the data-related questions we used to file Jira tickets for.

Security analytics. Our Bot Management team uses Town Lake to query ML scoring events with score > 0.9 in the last 48 hours filtered by ASN and geography. Threat researchers have built their own query toolkit on top of it. Trust & Safety pulls signals to help police abuse.

Customer support. “Find the top 100 billing support tickets from customers who have spent >$100” used to be a multi-day project. Now it’s a Skipper query.

What we have learned

A few things have surprised us.

Less prompting is more. Early versions of Skipper had elaborate, prescriptive system prompts: “First, use search_datasets. Then, use get_entity_details. Then, use list_schema_fields if needed…” Quality went down. The model is good at reasoning about analytical workflows; it doesn’t need to be micromanaged. We replaced the prescriptive prompts with high-level guidance and let the model pick its own path. Results got better.

Tool overlap is poison. We initially exposed every variant of every tool: three different “fetch results” tools, two “search” tools, several “list” tools. The model got confused and called the wrong one. We consolidated. Now fetch_results has a mode parameter (inject / display / both) instead of three separate tools. Every tool has a single reason to exist.

Code, not metadata, captures meaning. The biggest accuracy wins came when we started ingesting the actual SQL that produces a table, not just its schema. A customer_type column with values contract, paygo, free looks identical in either context, but the SQL tells you that customer_type defaults to paygo when Salesforce data is missing. That kind of context never lives in column descriptions.

Memory matters more than we expected. There is a long tail of corrections that look like “you have to filter for X like this” or “ignore tables tagged Y.” Without a memory layer, the agent rediscovers and re-learns these every conversation. With one, it gets monotonically better at the recurring questions a team actually asks.

The boring infrastructure is the hard part. Trino + Iceberg is not new technology. The hard work is in the boring stuff: per-row access control, default-closed table allowlisting, query auditing, time-bound credentials, PII detection, idempotent ingestion, schema evolution. Those are the things that make a data platform safe to actually use.

What’s next

We’re expanding the agent surface. Skipper already integrates as an MCP server into any IDE that supports it. The next step is deeper integration with our own internal chat and ticketing systems, so that “ask the data” becomes the natural first move for anyone debugging an incident, scoping a project, or sanity-checking a hypothesis.

We’re investing heavily in the Transformer pipeline. The goal is for any team at Cloudflare to be able to build a curated dataset with a few SQL files and a .meta.json description, deploy it as a Workflow, get it scheduled and monitored automatically, and have it surface in DataHub and Skipper without any additional work. The idea is self-serve data engineering, with the same shape as self-serve software engineering.

R2 SQL, Cloudflare’s serverless, distributed, analytics query engine, is getting more and more robust by the day. As its feature set expands, we plan to move many parts of Town Lake’s workflow over to it.

The bet we made — that the next breakthrough product comes from someone looking at the data and seeing something nobody else sees — is one we’re still betting on. Town Lake is how we make sure they can find it.