Post Syndicated from Kayalvizhi Kandasamy original https://aws.amazon.com/blogs/big-data/how-zepto-powers-sub-second-search-using-opensearch-service-or2-instances/
Sub-second search is the starting point of every order on Zepto, a fast-growing quick-commerce platform in India, founded in 2021 with endeavor to provide delivery in minutes. Powering the search experience is Amazon OpenSearch Service, a managed retrieval engine built on OpenSearch for agentic AI, search, and analytics.
Zepto operates hundreds of delivery hubs (dark stores) across Indian cities where it provides logistics services to sellers operating on Zepto Platform. Each hub maintains its own inventory levels, pricing, and assortment spanning thousands of Stock Keeping Units (SKUs). As the company scaled to hundreds of hubs, driving linear increases in indexing volume and maintaining sub-second product search latency while controlling costs became increasingly challenging.
To address this, Zepto migrated its OpenSearch Service data nodes from memory-optimized instances to OpenSearch Optimized instances. This instance family is purpose-built for high indexing throughput and cost efficiency. It uses local storage as the primary data tier, with Apache Lucene segments copied synchronously to Amazon Simple Storage Service (Amazon S3) for durability. With this migration, Zepto now serves the same workload with two-thirds of their previous data node count, achieving over 100% higher indexing throughput and 30% cost savings.
In this post, we explore the architecture decisions along with the load testing outcomes that led Zepto to select OpenSearch Optimized instances for latency-sensitive product search. We also discuss the key lessons learned during the production migration.
Zepto’s search platform
Zepto’s search platform is built around a localized delivery hub model. Each hub maintains its own inventory, capacity, and fulfillment priority. When a customer searches for a product, the query is not resolved against a global catalog. Instead, it is resolved in the context of the specific delivery hub or hubs serving that customer’s delivery address. This distinction is critical: Every customer journey on Zepto’s application begins with product discovery through search, browse, and promotional surfaces. All these must reflect hub-specific availability in real time to fulfill orders in minutes.
An event-driven architecture powers this experience, keeping results fresh as products, prices, offers, and inventory change across hundreds of delivery hubs. The following architecture diagram illustrates Zepto’s end-to-end indexing and search pipeline, from event production through stream processing to the search indices on OpenSearch Service.
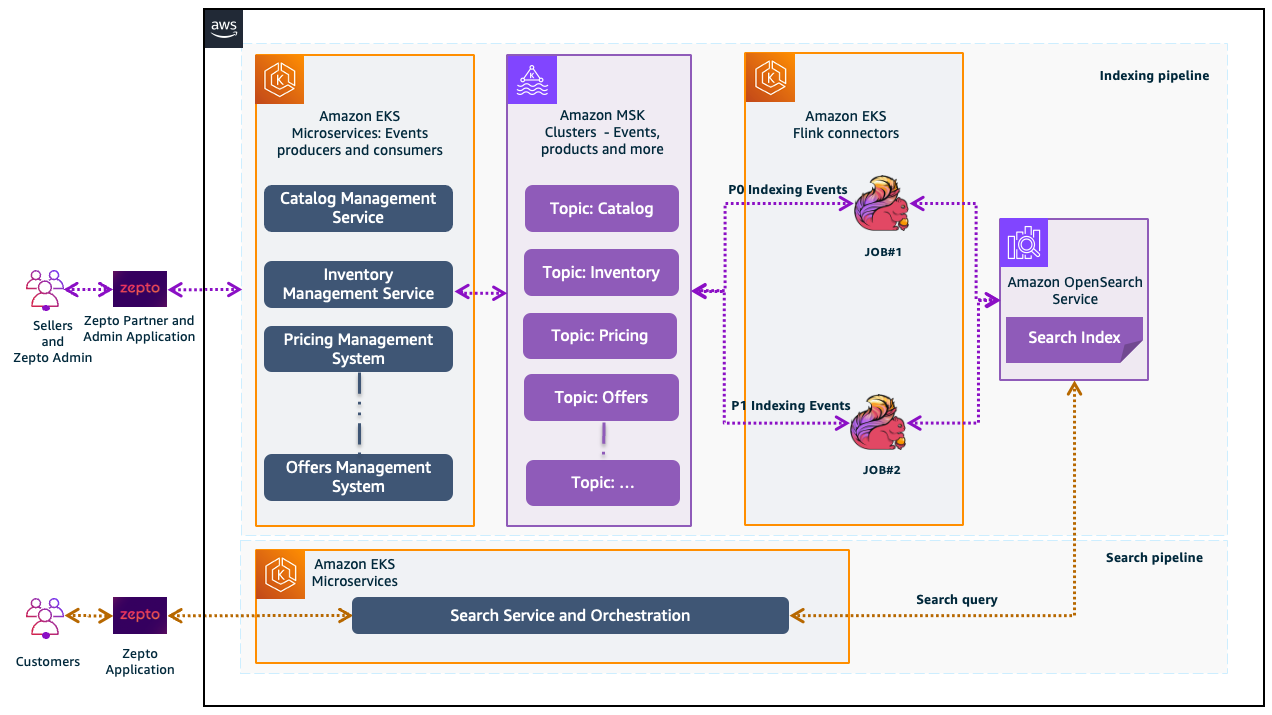
Figure 1: Zepto’s end-to-end indexing and search pipeline architecture
Event producers and consumers: Zepto’s application microservices are deployed on Amazon Elastic Kubernetes Service (Amazon EKS), a fully managed service for running Kubernetes workloads on AWS. These microservices serve as both event producers and consumers. Sellers and Zepto Admin users interact with the Zepto Partner and Admin application.
Key microservices: The Catalog Management Service emits events when product metadata changes like new product additions, attribute updates, and category reclassifications. The Inventory Management Service publishes stock-level changes across delivery hubs in real time as warehouse teams pick, pack, and replenish inventory. The Pricing Management Service generates events whenever sellers update pricing. The Offers Management Service broadcasts events when promotional offers are created, activated, modified, or expired. Together, these microservices capture every relevant update for downstream indexing, producing events into the streaming layer whenever business state changes.
Search events streaming: All domain events flow through Amazon Managed Streaming for Apache Kafka (Amazon MSK), a managed streaming data service that manages Apache Kafka infrastructure and operations.
The system organizes events into dedicated Kafka topics by business domain. These include Catalog for product metadata changes, Inventory for hub-level stock updates, Pricing for price changes across stores, and Offers for promotional offer lifecycle events and more. This topic-based partitioning provides independent scaling per domain, ensures ordered delivery within each topic and consumer isolation, so that a surge in inventory events does not disrupt catalog indexing.
Stream processing and routing: Events from MSK topics are consumed and routed into two priority-based indexing pipelines through dedicated Apache Flink OpenSearch Connector jobs deployed on an Amazon EKS cluster:
- Job #1: P0 indexing events (Pipeline #1): Processes high-priority events requiring near real-time index freshness, such as inventory changes, catalog enrichment, and pricing updates.
- Job #2: P1 indexing events (Pipeline #2): Handles lower-priority but higher-volume events, such as tag updates, semantic embedding generation, offer activations, and nightly revenue per impression (RPI) score recomputation. These updates improve search quality but can tolerate slightly higher latency.
With this dual-job approach, Zepto maintains sub-second freshness for critical signals like stock availability and current pricing. Compute-heavy enrichment updates are processed separately without creating backpressure on real-time updates.
Search indices: Zepto hosts the search index on OpenSearch Service, structured at the city-product level. Delivery hub-specific metadata, such as stock status and hub-level demand signals, is stored as nested documents within each record. The following example depicts a typical document in the search index.
The document structure supports store-level personalization while organizing the index by city-product pairs.
Search pipeline: Zepto’s search platform decouples the search request flow from the indexing pipeline at the application layer. When a customer initiates a search, the request passes through the Zepto application to the Search Service and Orchestration layer, which queries the OpenSearch index and assembles the response.
The Search Service and Orchestration layer handles the complete query lifecycle. This includes query understanding, candidate retrieval, machine learning (ML) ranking, ad slotting, and response assembly. For a detailed overview of Zepto’s full search architecture, refer to Building Search for a 10-Minute World on the Zepto engineering blog.
Scaling challenge
Zepto’s search platform started with a single use case, basic product search. As the business expanded, the platform introduced increasingly sophisticated experiences and each new experience added indexing signals to the pipeline like offer events, liquidation tags, pricing changes, ranking scores and more. All needed to be ingested and reflected in the index. Simultaneously, growing user traffic and the expansion of browse surfaces increased read throughput demands on the cluster.
The challenge was most acute during festive events like Diwali and New Year, when traffic surges required scaling to 1.4× the data node count. Although the cluster handled the node additions, the team needed to monitor shard relocation progress and validate that search latencies remained within service level agreements (SLAs) at each step. This operational overhead grew with each scaling event.
Adding more nodes to the cluster would address the immediate throughput constraints, but at the cost of proportionally higher infrastructure spend. To find a solution, Zepto set a clear goal: “Improve throughput without increasing the data node count.”
Solution overview
With the goal of keeping the node count intact, Zepto experimented with multiple configurations. One approach was resharding, adjusting the number of primary shards to better distribute the workload across existing nodes. However, load testing under production-representative traffic revealed that each resharding configuration degraded search latencies. The resharding operations themselves were also operationally expensive, requiring full index recreation, data migration, and extended validation windows.
The team needed a fundamentally different approach. The approach needed to improve throughput without adding nodes or resharding the index.
Evaluating OpenSearch Optimized instances
OpenSearch Optimized instances are an instance family purpose-built for workloads that require high indexing throughput with cost efficiency. They are commonly used for log analytics and time series use cases. These instances store data on Amazon Elastic Block Store (Amazon EBS) volumes for fast local access. Apache Lucene segments are synchronously replicated to Amazon S3, providing 11 nines of data durability.
Despite the common use case association with log analytics, we recommended evaluating OpenSearch Optimized instances type OR2 for Zepto’s product search workload. The team assessed two key criteria to determine viability:
Criterion 1: Does segment replication address the throughput bottleneck?
With document replication (the default on memory-optimized instances), every write is indexed on the primary shard and then re-indexed independently on each replica. This duplicates CPU work across the cluster. With segment replication on OpenSearch Optimized instances, segments are built once on the primary shard. They are then copied as complete files to replicas. This eliminates the duplicate indexing pipeline on replicas and frees their compute for serving search queries. Zepto’s workload involved continuous indexing from multiple pipelines that competed with search traffic. This separation was the key architectural advantage.
Criterion 2: Can the search platform tolerate the 10-second refresh interval?
OpenSearch Optimized instances use a 10-second segment replication refresh interval that is longer than the default one-second refresh on memory-optimized instances. This means newly indexed documents become searchable with up to 10 seconds of additional delay. The team evaluated whether this trade-off was acceptable for their search use cases.
Rahul Pradeep, Senior Architect at Zepto, explains:
“Out-of-stock or in-stock is not a primary parameter for retrieval. It is more like a tiebreaker. Relevance is our primary parameter. We retrieve hundreds of products in one query and then do a last-minute validation against our real-time inventory service. That is why we may not need one-second refresh.”
Zepto’s existing architecture where the Product Enrichment Service validates inventory after retrieval indicated that the 10-second refresh interval would not impact customer experience; see how Zepto built Product Enrichment at scale for further details. The migration was viable without any application-level changes.
Based on this evaluation, the solution involved migrating from memory-optimized Graviton-based data nodes to OpenSearch Optimized instances. This shift changed how indexing work is distributed across the cluster. Instead of a model where every node duplicates the full indexing pipeline, only the primary shard performs indexing, and replicas receive pre-built segments.
Load testing
To validate the hypothesis before committing to a migration, we designed a proof of concept, a load testing setup in their lower environment that mirrored production characteristics:
- Baseline cluster with r7g.12xlarge instances and a parallel testing cluster with or2.12xlarge instances, having four nodes per cluster.
- Identical shard configuration (X primary shards, Y replica, Z shard copies per node).
- Simultaneous indexing and read load simulation.
Document structure improvements
In addition to validating the infrastructure change, the team identified an opportunity to optimize the document structure itself to further improve search latency. They added an active_hubs attribute to the base document, a flat array listing only the hubs where the product is currently stocked and active as shown in the following updated document structure.
The following table summarizes the key metrics from the load test comparing the r7g.12xlarge baseline cluster against the or2.12xlarge test cluster under identical conditions.
| Metric | r7g.12xlarge | or2.12xlarge | Change |
| Peak indexing lag | ~12M docs | ~6M docs | 2X Faster |
| Indexing throughput | Baseline | 2× higher | 100% Improvement |
| Search latency (p90) | 187 ms | 89.1 ms | 52% Improvement |
| Search latency (p99) | 244 ms | 175 ms | 28% Improvement |
The following graph depicts the P90 search latency comparison between the two clusters.
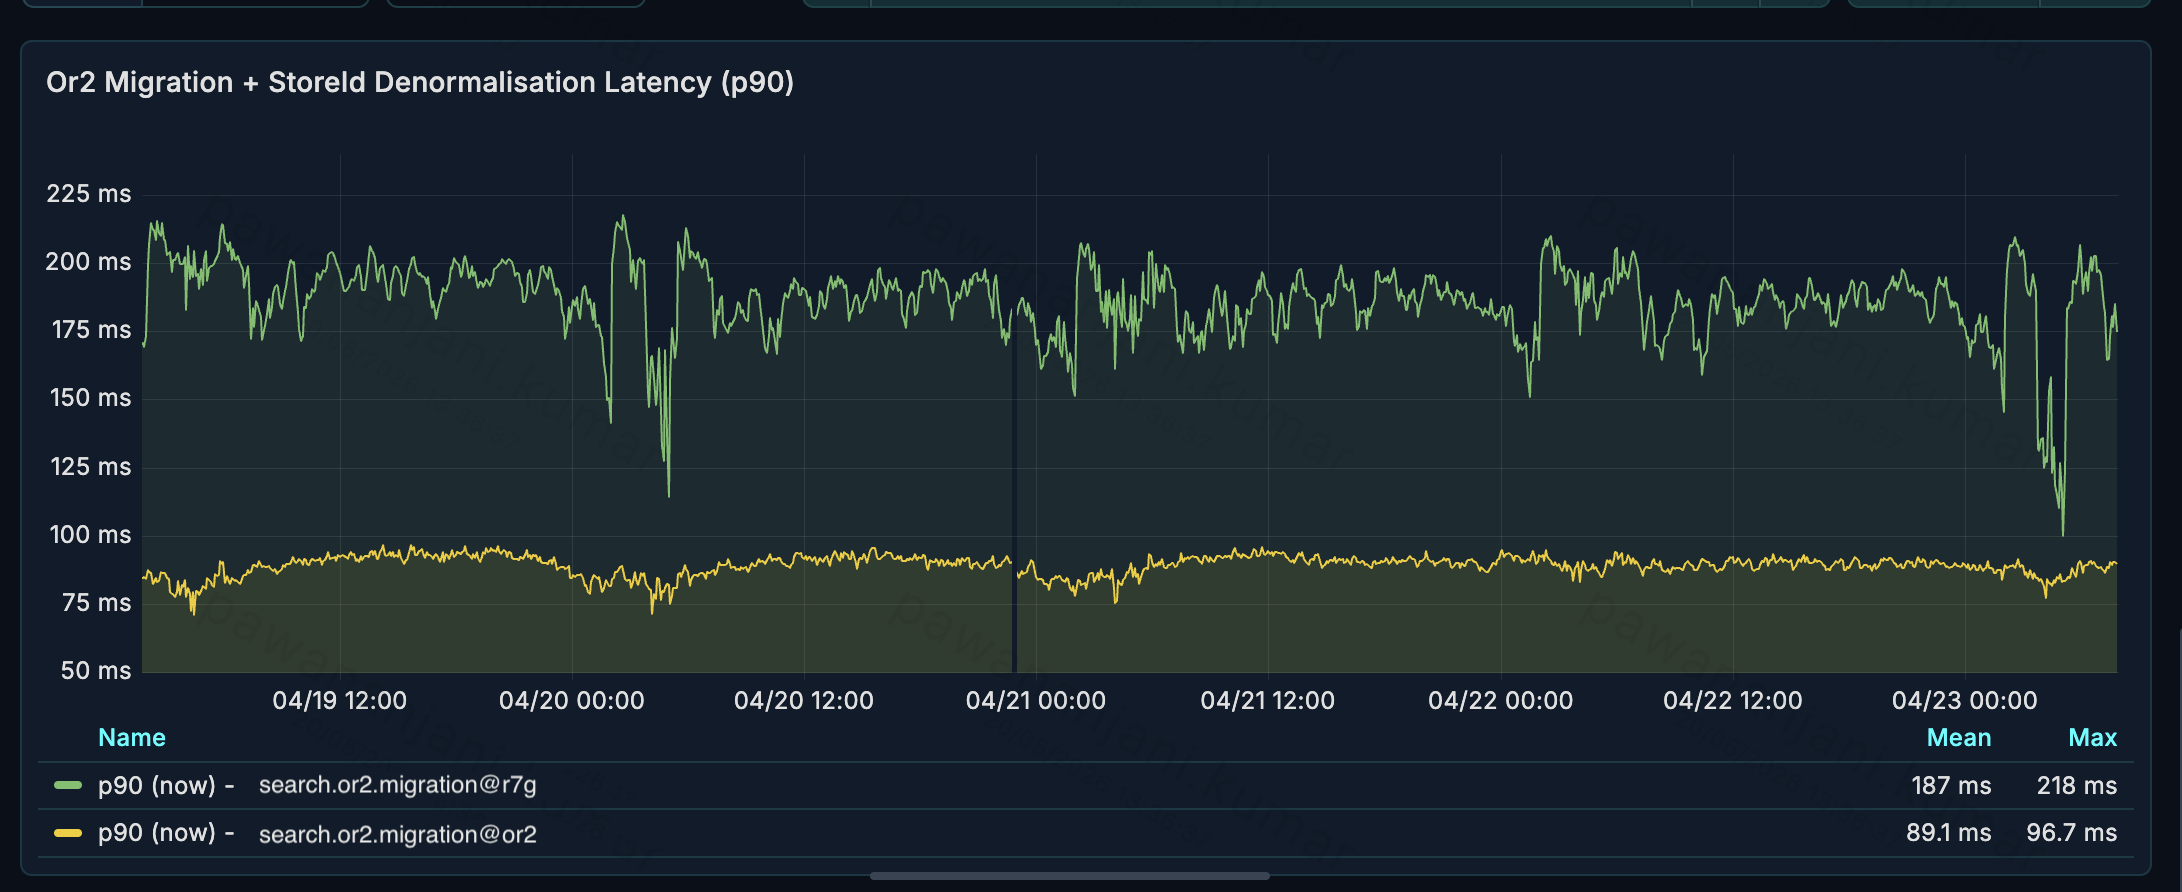
Figure 2: P90 search latency comparison between the r7g and OR2 clusters
The following graph depicts the P99 search latency comparison between the two clusters.
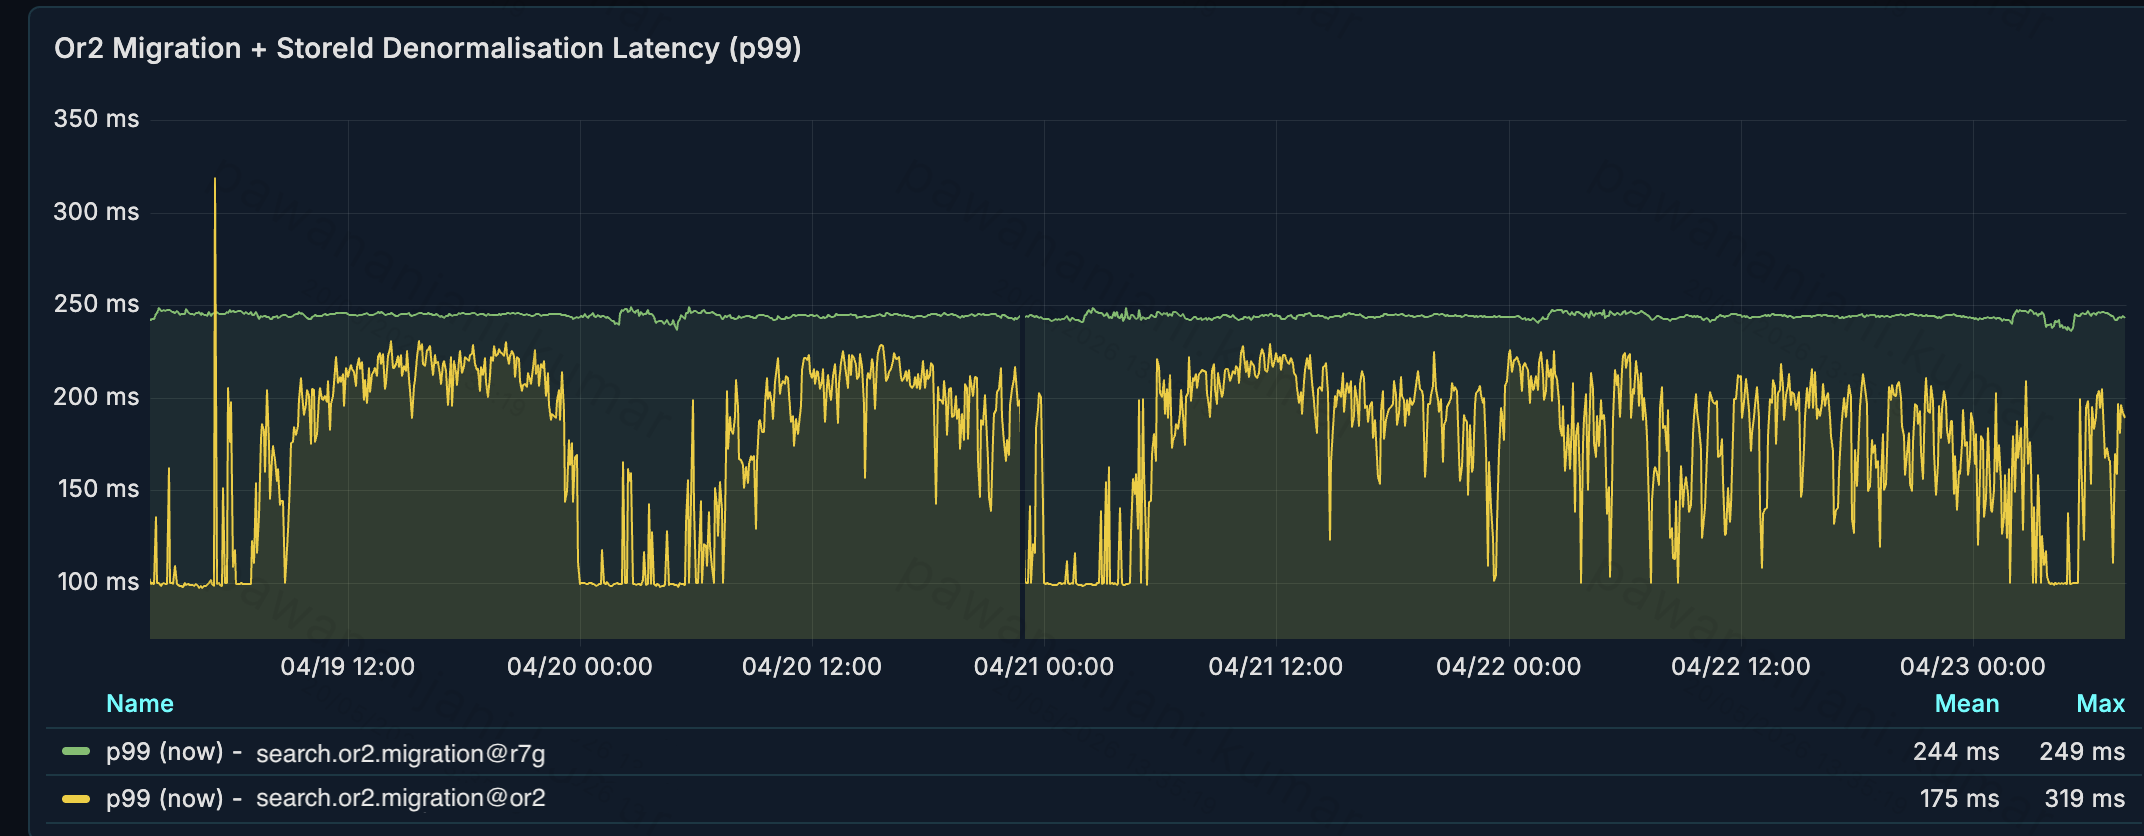
Figure 3: P99 search latency comparison between the r7g and OR2 clusters
The following graphs depict the indexing latency comparison between the two clusters.
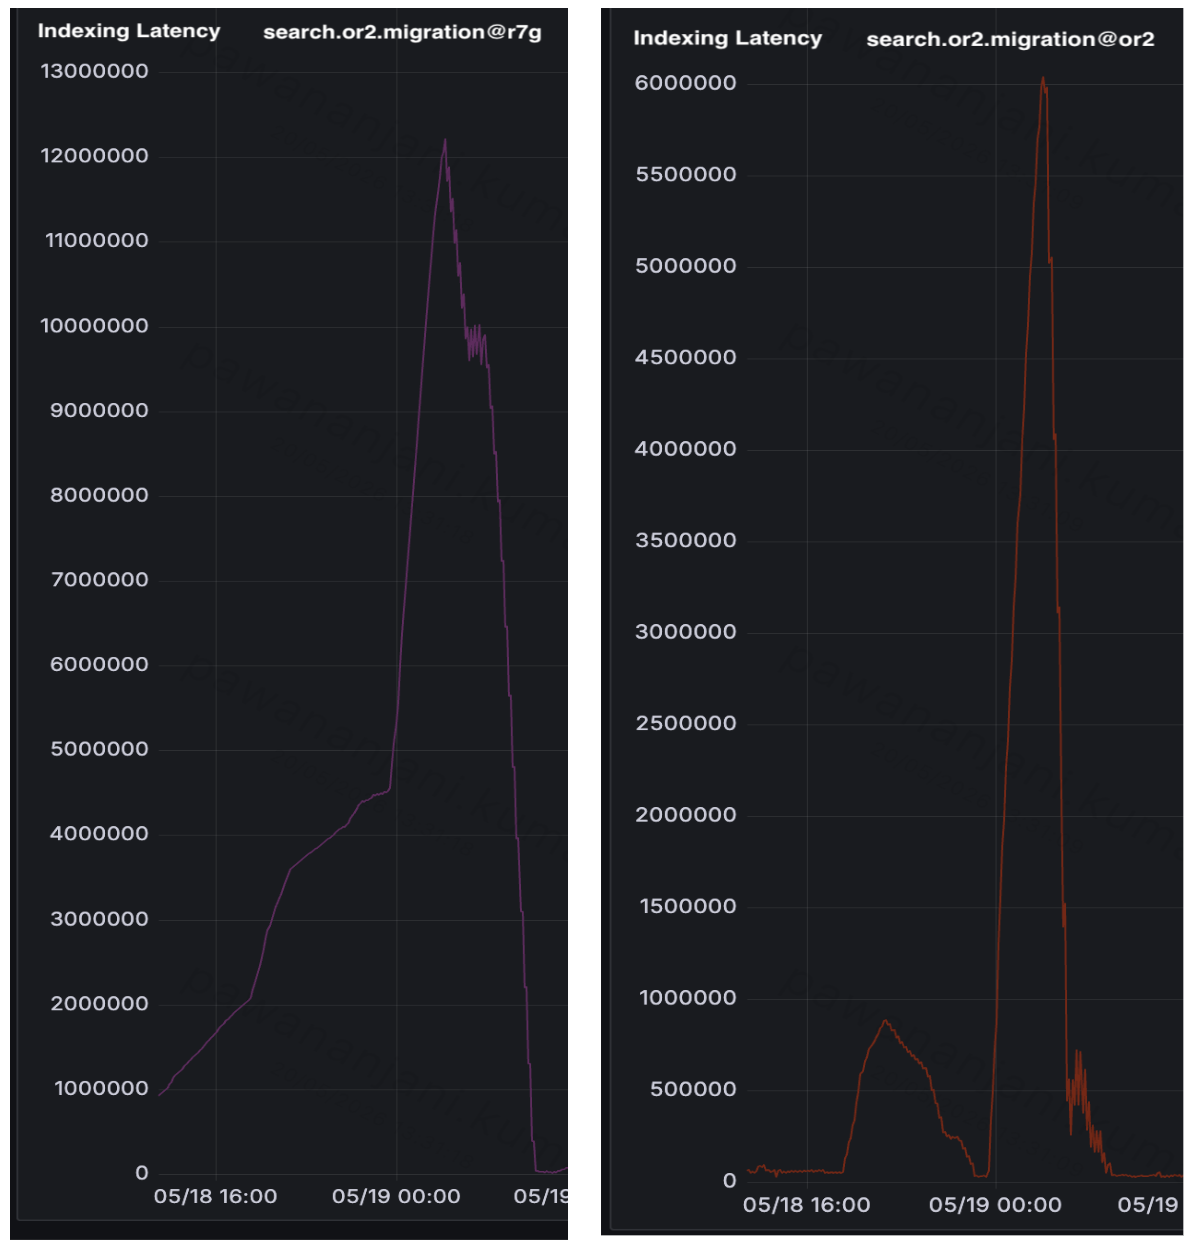
Figure 4: Indexing latency comparison between the r7g (left) and OR2 (right) clusters
Key insights
- Improvement in indexing throughput: The higher indexing throughput of OR2 is most visible during nightly batch operations when events from RPI score recomputation, tag updates, and catalog enrichment flood the indexing pipeline simultaneously. On the r7g cluster, the P1 indexing lag peaked at over 12M docs. On OR2, with approximately 2× the indexing throughput, the same event volume produced a peak lag of only 6M docs. Higher throughput translates directly to lower lag and fresher search results. It is attributed to the segment replication approach of OR2 that eliminates redundant indexing work on replicas. Each document is indexed once on the primary shard rather than being replayed on each replica.
- Reduction in search latency: P90 search latency dropped from 187 ms to 89.1 ms (52% improvement) and P99 from 244 ms to 175 ms (28% improvement). These gains are primarily attributable to the
active_hubsdocument structure change rather than the instance type migration alone. By pre-computing a flat list of active hubs at index time, the query no longer needs to traverse nested hub documents to determine availability. This creates a lightweight pre-filter that eliminates unnecessary computation at search time.
Production planning and rollout
The load test results gave Zepto the confidence to make a key architectural decision: reduce the overall data node count. Higher per-node indexing throughput meant the same workload could be served with fewer nodes with OR2, and the cost savings compounded. Each eliminated node removed compute, storage, and operational overhead from the cluster. Zepto carried this forward into production, provisioning the OR2 cluster at two-thirds of the original node count. The following table summarizes the before-and-after comparison.
| Metric | r7g.12xlarge | or2.12xlarge | Change |
| Data nodes required | 3X Nodes | 2X Nodes | -33.3% |
| Cost savings | Baseline | 2/3 of Baseline | +30% |
Rather than a complete cutover, Zepto adopted a phased rollout strategy using bucket-based traffic routing, completing the migration over approximately two months with zero downtime:
- Provisioned a new OpenSearch Service domain on OR2 instances with segment replication turned on.
- Executed parallel indexing pipelines to populate the OR2 cluster while the existing r7g cluster continued serving production traffic.
- Routed internal users to the OR2 cluster first to validate search quality, relevance, and latency characteristics under real query patterns.
- Gradually increased external user traffic in buckets, monitoring comparison dashboards at each increment for latency regressions or relevance drift.
- Maintained parallel dashboards throughout the migration to compare the OR2 and r7g clusters in real time. Key metrics monitored included p50 and p99 search latency, indexing throughput, replica lag, Java Virtual Machine (JVM) heap utilization, circuit breaker events, I/O operations per second (IOPS) utilization, and disk throughput.
Challenges and lessons learned
During the migration, the team encountered one notable challenge: latency spikes during segment merges. This observation offers practical guidance for teams evaluating OpenSearch Optimized instances for search workloads.
Symptom: After shifting significant traffic to OR2, Zepto observed intermittent p99 latency spikes correlating with segment merge operations.
Root cause: Large segment merges consumed significant I/O bandwidth, temporarily impacting concurrent search query performance. The original 256 GB EBS volumes did not provide sufficient IOPS buffer for concurrent merge and search operations.
Resolution: Implemented the following two changes:
- Increased EBS volume size to 1 TB per node. For gp3 volumes, baseline IOPS increase with volume size. This provided buffer for concurrent operations.
- Tuned the segment merge policy. Reduced
max_merged_segment(see OpenSearch: Force Merge API for more details) from 5 GB to 2 GB andsegments_per_tier(see OpenSearch: Index Settings for more details) from 10 to 5. This produces smaller, more frequent merges that distribute I/O load more evenly rather than infrequent large merges that spike latency.
After increasing EBS volume size and tuning the segment merge policy, latency spikes decreased. Transient spikes still occurred during merges but settled quickly within acceptable bounds.
Production cutover
Finally, Zepto shifted from partial to 100% traffic over four weeks and decommissioned the previous cluster after confirming stable performance across multiple peak traffic cycles. The following table summarizes the cluster configuration before and after migration.
| Parameter | Previous Cluster | Current Cluster |
| Instance type | r7g.12xlarge | or2.12xlarge |
| Data nodes | 3X Nodes | 2X Nodes |
| RAM per node | 384 GiB | 384 GiB |
| Replication strategy | Document replication | Segment replication |
| Default refresh interval | 1 Second | 10 Seconds |
| Durability | Cross-Availability Zone replicas | S3 synchronous replication |
Conclusion
In this post, we described Zepto’s evaluation of OpenSearch Optimized instances for latency-sensitive product search and the results of their production migration. By moving from memory-optimized data nodes to OpenSearch Optimized instances with segment replication enabled, Zepto achieved over 100% higher indexing throughput and 30% cost savings while reducing their cluster to two-thirds of the previous data node count.
Zepto’s migration demonstrates that OpenSearch Optimized instances are a viable choice for latency-sensitive product search and not just log analytics. Workloads where the retrieval layer can tolerate seconds-level staleness because real-time consistency is resolved at a different layer are candidates for adopting OR2 instances. For ecommerce and quick-commerce platforms that separate candidate generation from availability validation, this pattern can deliver significant infrastructure cost reduction.
If your workload has high indexing volume, and can tolerate a 10-second refresh interval, consider evaluating OpenSearch Optimized instances for your cluster. To get started:
- Assess your workload fit: review your current indexing throughput, replica count, and refresh interval requirements. Prioritize this approach if your workload has a high write-to-read ratio.
- Execute a proof of concept: provision a small OpenSearch Optimized cluster in a lower environment with identical shard configuration and restore a production index snapshot. Execute simultaneous indexing and search load to validate throughput and latency.
- Plan a phased rollout: use parallel indexing and bucket-based traffic routing to migrate incrementally with zero downtime, monitoring indexing lag and search latency at each step.
To explore the architecture behind OpenSearch Optimized instances, see Under the Hood: OpenSearch Optimized Instances. For practical configuration guidance, see Improve performance with OpenSearch Optimized Instances. We welcome your questions and feedback in the comments section below.