Post Syndicated from Lennart Poettering original https://0pointer.net/blog/photos/kata-tjuta.html
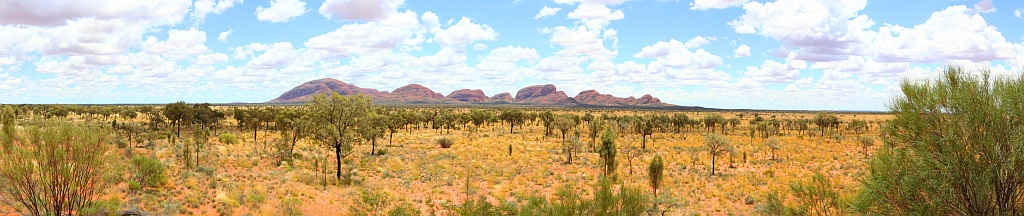
Post Syndicated from Lennart Poettering original https://0pointer.net/blog/photos/kata-tjuta.html
Post Syndicated from Lennart Poettering original https://0pointer.net/blog/projects/lca2008.html
After coming back from my somewhat extended linux.conf.au trip I spent the
whole day grepping through email. Only 263 unprocessed emails left in my inbox.
Yay.
PRTPILU
Thanks to the LCA guys, video footage is now available of all talks,
including my talk
Practical Real-Time Programming in Linux Userspace (Theora,
Slides).
In my endless modesty I have to recommend: go, watch it, it contains some
really good stuff (including me not being able to divide 1 by 1000). Right now,
the real-time features of the Linux kernel are seldomly used on the desktop due
to a couple of reasons, among them general difficulty and unsafety to use them
but predominantly it’s probably just unawareness. There are a couple of
situations however, where scheduling desktop processes as RT makes a lot of
sense (think of video playback, mouse curse feedback, etc.), to decouple the
execution (scheduling) latency from the system load. This talk focussed mostly
on non-trivial technical stuff and all the limitations RT on Linux still has.
To fully grok what’s going on you thus need some insight into concurrent
programming and stuff.
My plan is to submit a related talk to GUADEC wich will focus more on
actually building RT apps for the desktop, in the hope we will eventually be
able to ship a desktop with audio and video that never skips, and where user
feedback is still snappy and quick even if we do the most complicated IO
intensive processing in lots of different processes in the background on slow
hardware.
I didn’t have time to go through all my slides (which I intended that way
and is perfectly OK), so you might want to browse through my slides even if you
saw the whole clip. The slides, however, are not particularly verbose.
Rumors
Regarding all those
rumors
that have been spread while I — the maintainer of PulseAudio — was in the
middle of the australian outback, fist-fighting with kangaroos near Uluru: I
am not really asking anyone to port their apps to the native PulseAudio API right now. While I do think
the API is quite powerful and not redundant, I also acknowledge that it is
very difficult to use properly (and very easy to misuse), (mostly) due to its
fully asynchronous nature. The mysterious libsydney project is
supposed to fix this and a lot more. libsydney is mostly the Dukem Nukem
Forever of audio APIs right now, but in contrast to DNF I didn’t really
announce it publicly yet, so it doesn’t really count. 😉 Suffice to
say, the current situation of audio APIs is a big big mess. We are working on
cleaning it up. For now: stick to the well established and least-broken APIs,
which boils down to ALSA. Stop using the OSS API now! Don’t program
against the ESD API (except for event sounds). But, most importantly: please
stop misusing the existing APIs. I am doing my best to allow all current APIs
to run without hassles on top of PA, but due to the sometimes blatant misues,
or even brutal violations of those APIs it is very hard to get that working
for all applications (yes, that means you, Adobe, and you, Skype). Don’t
expect that mmap is available on all audio devices — it’s not, and especially
not on PA. Don’t use /proc/asound/pcm as an API for enumerating audio
devices. It’s totally unsuitable for that. Don’t hard code device strings. Use
default as device string. Don’t make assumptions that are not and
cannot be true for non-hardware devices. Don’t fiddle around with period
settings unless you fully grok them and know what you are doing. In short: be
a better citizen, write code you don’t need to be ashamed of. ALSA has its
limitations and my compatibility code certainly as well, but this is not an
excuse for working around them by writing code that makes little children cry.
If you have a good ALSA backend for your program than this will not only fix
your issues with PA, but also with Bluetooth, you will have less code to
maintain and also code that is much easier to maintain.
Or even shorter: Fix. Your. Broken. ALSA. Client. Code. Thank you.
Oh, if you have questions regarding PA, just ping me on IRC (if I am
around) or write me an email, like everyone else. Mysterious, blogged pseudo
invitations to rumored meetings is not the best way to contact me.
Post Syndicated from Lennart Poettering original https://0pointer.net/blog/ich-bin-ein-berliner.html
To whom it may concern: I finally moved from Hamburg (Wohldorf) into my new flat in Berlin (Friedrichshain).
Post Syndicated from Lennart Poettering original https://0pointer.net/blog/projects/svn-git.html
To whom it may concern: as a first step to move away from SVN and towards
GIT for all my code, I have now configured live GIT mirrors for all my SVN repositories. The plan is to move fully
to GIT, but not as long as the GIT integration into Trac is as painful as it is
right now. The scripts I used to initialize and update the mirrors are svn-live-init and svn-live-update, for those
interested. They are based on scripts CJ van den Berg supplied me with.
It would be great to have the mirror to be both ways. Lazyweb, do you know how to do that?
Post Syndicated from Lennart Poettering original https://0pointer.net/blog/projects/avahi-distcc.html
I finally found them time to sit down and update my venerable Avahi/Zeroconf patch for
distcc. A patched distcc
automatically discovers suitable compiler servers on the local network, without
the need to manually configure them. (Announcement).
Here’s a quick HOWTO for using a patched distcc like this:
If this doesn’t work for you than it is a good idea to run distcc
--show-hosts to get a list of discovered distcc servers. If this list
isn’t complete then this is most likely due to mismatching GCC versions or
architectures. To check if that’s the case use avahi-browse -r
_distcc._tcp and compare the values of the cc_machine and
cc_version fields. Please note that different Linux distributions use
different GCC machine strings. Which is expected since GCC is usually patched quite
a bit on the different distributions. This means that a Fedora distcc
(the client) will not find a Debian distccd (the server) and vice
versa. But again: that’s a feature, not a bug.
The new -j and --show-hosts options for distcc are useful for non-zeroconf setups, too.
The patch will automatically discover the number of CPUs on remote machines
and make use of that information to better distribute jobs.
In short: Zeroconf support in distcc is totally hot, everyone should have it!
For more information have a look on the announcement of my original
patch from 2004 (at that time for the historic HOWL Zeroconf daemon), or read the new
announcement linked above.
Distribution packagers! Please merge this new patch into your packages! It
would be a pity to withhold Zeroconf support in distcc from your users any
longer!
Unfortunately, Fedora doesn’t include any distcc packages. Someone should be
changing that (who’s not me ;-)).
You like this patch? Then give me a kudo on ohloh.net. Now that I earned a golden 10 (after kicking Larry Ewing from position 64. Ha, take that Mr. Ewing!), I need to make sure I don’t fall into silver oblivion again. 😉
Post Syndicated from Lennart Poettering original https://0pointer.net/blog/projects/avahi-0.6.22.html
A couple of minutes ago I released Avahi
0.6.22 into the wild, the newest iteration of everyone’s favourite zero
configuration networking suite.

You ask why this is something to blog about?
Firstly, new in this version is Sjoerd Simons’ avahi-gobject
library, a GObject wrapper around the Avahi API. It allows full GObject-style
object oriented programming of Zeroconf applications, with signals and
everything. To all you GNOME/Gtk+ hackers out there: now it is even more fun to
hack your own Zeroconf applications for GNOME/Gtk+!
Secondly, this is the first release to ship i18n support. For those who
prefer to run their systems with non-english locales[1] this should
be good news. I’ve always been a little afraid of adding i18n support, since
this either meant that I would have contstantly had to commit i18n patches, or that I
would have needed to move my code to GNOME SVN. However, we now have Fedora’s Transifex,
which allows me to open up my SVN for translators without much organizational
work on my side. Translations are handled centrally, and commited back to my
repository when needed. It’s a bit like Canonical’s Rosetta, but with a focus
on commiting i18n changes upstream, and without being closed-source crap.
You like this release? Then give me a kudo on ohloh.net. My
ego still thirsts for gold, and I am still (or again) 25 positions away from
that. 😉
Footnotes
[1] Personally, I run my desktop with $LC_MESSAGES=C, but
LANG=de_DE, which are the settings I can recommend to everyone who is from Germany and wants to stay
sane. Unfortunately it is a PITA to configure this on
GNOME, though.
Post Syndicated from Lennart Poettering original https://0pointer.net/blog/photos/india.html
FOSS.in was one of the best conferences I have ever
been to, and a lot of fun. The organization was flawless and I can
only heartily recommend everyone to send in a presentation proposal for next year’s
iteration. I certainly hope the commitee is going to accept my proposals next year again. Especially the food was gorgeous.
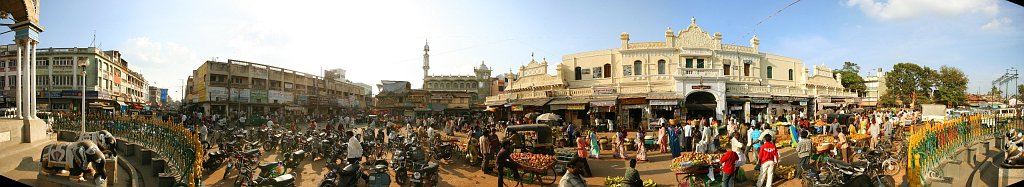
I will spare you the usual conference photos, you can find a lot of those on flickr. However, what I will not spare you are a couple of photos I shot in Bangalore, Srirangapatna and Mysore.


Post Syndicated from Lennart Poettering original https://0pointer.net/blog/felix-america.html
These two lenses cost EUR 679 resp. EUR 386.45 at amazon.de.
On amazon.com you can get them for US$ 639, resp. US$ 289.95.
At today’s courses that’s 430 EUR, resp. 195 EUR.
Americans pay 63%, resp. 50% of what Germans have to pay for these lenses. How unfair! 🙁
Post Syndicated from Lennart Poettering original https://0pointer.net/blog/projects/pgrp-vs-session.html
Dear Lazyweb,
I have trouble understanding what exactly POSIX process groups and sessions
are good for. The POSIX
docs
are very vague on this. What exactly is the effect of being in a process
group with some other process, and what does being in the same session with it
add on top? And what is the benefit of being a group/session leader in contrast of just being a normal random process in the group/session?
The only thing I understood is that kill(2) with a negative first
parameter can be used to “multicast” signals to entire process groups, and that
SIGINT on C-c is delivered that way. But, is that all? The POSIX docs say
“… for the purpose of signaling, placement in foreground or background,
and other job control actions“, which is very vague. What are those
“other job control actions?“. What does job control persist of besides
multicasting signals? And what is “placement in foreground or background” other
than delivering signals?
And I totally don’t get POSIX sessions and how they differ from POSIX process groups. Please enlighten me!
Puzzled,
Lennart
Post Syndicated from Lennart Poettering original https://0pointer.net/blog/projects/atomic-rt.html
Unfortunately not all CPU architectures have native support for atomic
operations, or only support a very limited subset. Most
prominently ARMv5 (and
older) hasn’t any support besides the most basic atomic swap
operation[1]. Now, more and more free code is starting to
use atomic operations and lock-free
algorithms, one being my own project, PulseAudio. If you have ever done real-time
programming you probably know that you cannot really do it without
support for atomic operations. One question remains however: what to
do on CPUs which support only the most basic atomic operations
natively?
On the kernel side atomic ops are very easy to emulate: just disable
interrupts temporarily, then do your operation non-atomically, and afterwards
enable them again. That’s relatively cheap and works fine (unless you are on SMP — which
fortunately you usually are not for those CPUs). The Linux
kernel does it this way and it is good. But what to do in user-space, where you cannot just go and disable interrupts?
Let’s see how the different userspace libraries/frameworks do it
for ARMv5, a very relevant architecture that only knows an atomic swap (exchange)
but no CAS
or even atomic arithmetics. Let’s start with an excerpt from glibc’s
atomic operations implementation for ARM:
/* Atomic compare and exchange.  These sequences are not actually atomic;
   there is a race if *MEM != OLDVAL and we are preempted between the two
   swaps.  However, they are very close to atomic, and are the best that a
   pre-ARMv6 implementation can do without operating system support.
   LinuxThreads has been using these sequences for many years.  */
This comment says it all. Not good. The more you make use of atomic
operations the more likely you’re going to to hit this race. Let’s
hope glibc is not a heavy user of atomic operations. PulseAudio however is, and
PulseAudio happens to be my focus.
Let’s have a look on how Qt4
does it:
extern Q_CORE_EXPORT char q_atomic_lock;

inline char q_atomic_swp(volatile char *ptr, char newval)
{
    register int ret;
    asm volatile("swpb %0,%1,[%2]"
                 : "=&r"(ret)
                 : "r"(newval), "r"(ptr)
                 : "cc", "memory");
    return ret;
}

inline int q_atomic_test_and_set_int(volatile int *ptr, int expected, int newval)
{
    int ret = 0;
    while (q_atomic_swp(&q_atomic_lock, ~0) != 0);
    if (*ptr == expected) {
	*ptr = newval;
	ret = 1;
    }
    q_atomic_swp(&q_atomic_lock, 0);
    return ret;
}
So, what do we have here? A slightly better version. In standard
situations it actually works. But it sucks big time, too. Why? It
contains a spin lock: the variable q_atomic_lock is used for
locking the atomic operation. The code tries to set it to non-zero,
and if that fails it tries again, until it succeeds, in the hope that
the other thread — which currently holds the lock — gives it up. The
big problem here is: it might take a while until that happens, up to
1/HZ time on Linux. Usually you want to use atomic operations to
minimize the need for mutexes and thus speed things up. Now, here you
got a lock, and it’s the worst kind: the spinning lock. Not
good. Also, if used from a real-time thread the machine simply locks
up when we enter the loop in contended state, because preemption is
disabled for RT threads and thus the loop will spin forever. Evil. And
then, there’s another problem: it’s a big bottleneck, because all
atomic operations are synchronized via a single variable which is
q_atomic_lock. Not good either. And let’s not forget that
only code that has access to q_atomic_lock actually can
execute this code safely. If you want to use it for
lock-free IPC via shared memory this is going to break. And let’s not
forget that it is unusable from signal handlers (which probably
doesn’t matter much, though). So, in summary: this code sucks,
too.
Next try, let’s have a look on how glib
does it:
static volatile int atomic_spin = 0;

static int atomic_spin_trylock (void)
{
  int result;

  asm volatile (
    "swp %0, %1, [%2]\n"
    : "=&r,&r" (result)
    : "r,0" (1), "r,r" (&atomic_spin)
    : "memory");
  if (result == 0)
    return 0;
  else
    return -1;
}

static void atomic_spin_lock (void)
{
  while (atomic_spin_trylock())
    sched_yield();
}

static void atomic_spin_unlock (void)
{
  atomic_spin = 0;
}

gint
g_atomic_int_exchange_and_add (volatile gint *atomic,
			       gint           val)
{
  gint result;

  atomic_spin_lock();
  result = *atomic;
  *atomic += val;
  atomic_spin_unlock();

  return result;
}
Once again, a spin loop. However, this implementation makes use of
sched_yield() for asking the OS to reschedule. It’s a bit
better than the Qt version, since it doesn’t spin just burning CPU,
but instead tells the kernel to execute something else, increasing the
chance that the thread currently holding the lock is scheduled. It’s a
bit friendlier, but it’s not great either because this might still delay
execution quite a bit. It’s better then the Qt version. And probably
one of the very few ligitimate occasions where using
sched_yield() is OK. It still doesn’t work for RT — because
sched_yield() in most cases is a NOP on for RT threads, so
you still get a machine lockup. And it still has the
one-lock-to-rule-them-all bottleneck. And it still is not compatible
with shared memory.
Then, there’s libatomic_ops. It’s
the most complex code, so I’ll spare you to paste it here. Basically
it uses the same spin loop. With three differences however:
It’s certainly the best implementation of the ones discussed here:
It doesn’t suffer by the one-lock-to-rule-them-all bottleneck. It’s
(supposedly) signal handler safe (which however comes at the cost of
doing two syscalls on every atomic operation — probably a very high
price). It actually works on RT, due to sleeping for an explicit
time. However it still doesn’t deal with priority
inversion problems — which is a big issue for real-time
programming. Also, the time slept in the select() call might
be relatively long, since at least on Linux the time passed to
select() is rounded up to 1/HZ — not good for RT either. And
then, it still doesn’t work for shared memory IPC.
So, what do we learn from this? At least one thing: better don’t do
real-time programming with ARMv5[2]. But more practically, how
could a good emulation for atomic ops, solely based on atomic swap
look like? Here are a few ideas:
Yepp, that’s as good as it gets. Unfortunately I cannot serve you
the optimal solution on a silver platter. I never actually did
development for ARMv5, this blog story just sums up my thoughts on all
the code I saw which emulates atomic ops on ARMv5. But maybe someone
who actually cares about atomic operations on ARM finds this
interesting and maybe invests some time to prepare patches for Qt,
glib, glibc — and PulseAudio.
Update: I added two more ideas to the list above.
Update 2: Andrew Haley just posted something like the optimal solution for the problem. It would be great if people would start using this.
Footnotes
[1] The Nokia 770 has an ARMv5 chip, N800 has ARMv6. The OpenMoko phone apparently uses ARMv5.
[2] And let’s not even think about CPUs which don’t even have an atomic swap!
[3] Which however you probably won’t, given that they’re only available on x86 on stable Linux kernels for now — but still, it’s cleaner.
Post Syndicated from Lennart Poettering original https://0pointer.net/blog/photos/montreal-rain.html
Sometimes, rain can be quite beautiful.
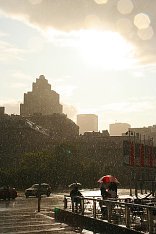
I took these during my stay at Montreal after OLS 2007. Which reminds me: don’t miss my talks at foss.in 2007, linux.conf.au 2008 and FOMS 2008. I’ll be speaking about Avahi, PulseAudio and practical real-time programming in userspace.
Post Syndicated from Lennart Poettering original https://0pointer.net/blog/projects/fedora-interview.html
Don’t miss this interesting Fedora interview with yours truly, where I go a bit into detail what’s coming next for PulseAudio.
Post Syndicated from Lennart Poettering original https://0pointer.net/blog/projects/pa-097.html
A few minutes ago, I finally released PulseAudio 0.9.7. Changes are numerous,
especially internally where the core is now threaded and mostly lock-free.
Check the rough list on the milestone page, announcement email. As many of you
know we are shipping a pre-release of 0.9.7 in Fedora 8, enabled by default. The final release
offers quite a few additions over that prerelease. To show off a couple of nice features, here’s a screencast, showing hotplug, simultaneous playback (what Apple calls aggregation) and zeroconfish network support:

Please excuse the typos. Yes, I still use XMMS, don’t ask [1]. Yes, you
need a bit of imagination to fully appreciate a screencast that lacks an audio track — but demos audio software.
So, what’s coming next? Earcandy, timer-based scheduling/”glitch-free” audio, scriptability through Lua, the todo list is huge. My unnoffical, scratchy, partly german TODO list for PulseAudio is available online.
As it appears all relevant distros will now move to PA by default. So,
hopefully, PA is coming to a desktop near you pretty soon. — Oh, you are one
of those who still don’t see the benefit of a desktop sound server? Then,
please reread this too
long email of mine, or maybe this
ars.technica article.
OTOH, if you happen to like this release, then consider giving me a kudo on ohloh.net, my ego wants a golden 10. 😉

Footnotes:
[1] Those music players which categorize audio by ID3 tags just don’t
work for me, because most of my music files are very badly named. However, my
directory structure is very well organized, but all those newer players don’t
care about directory structures as it seems. XMMS doesn’t really either, but
xmms . does the job from the terminal.
Flameeyes, thank’s for hosting this clip.
Post Syndicated from Lennart Poettering original https://0pointer.net/blog/glowing-sun.html
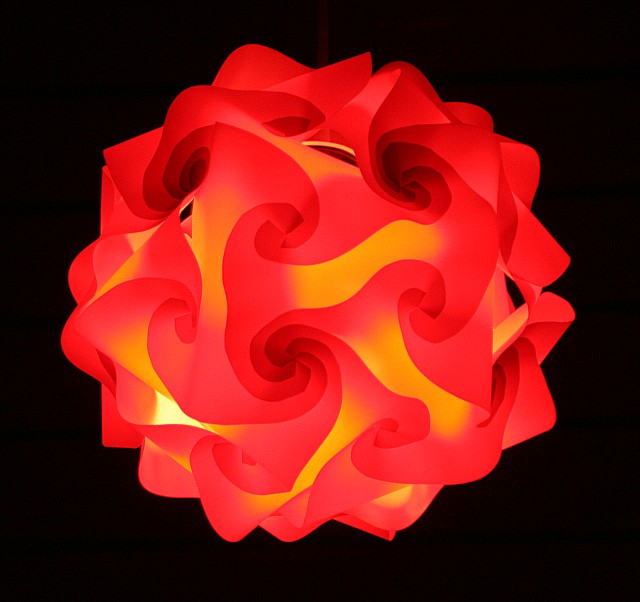
Danish-Mexican design,
this time in built from red ibico PolyOpaque; for your stylish and very
personal red light district.
Post Syndicated from Lennart Poettering original https://0pointer.net/blog/projects/lassi-lassi-popassi.html
Zeeshan,
Mango Lassi tastes a lot different than a milk shake, believe me! Also,
even if Mango Lassi was actually a western thing, do you know that just
recently I was witness of Sjoerd[1] ordering a Vindaloo Pizza
(or was it Korma?) at a Boston restaurant — italian pizza with indian-style curry on top. Now, that’s what some people
might be calling “ignorant of indian cuisine”. But actually I think that, like
in music, mixing different styles, combining things from different origins is a
good thing, and is what makes culture live.
Post Syndicated from Lennart Poettering original https://0pointer.net/blog/projects/mango-lassi-icon.html
Thanks to Vinicius Depizzol‘s great work, Mango Lassi now has an icon:

Muito obrigado!
I’d also like to thank everyone else who sent in an icon suggestion. Thank you very much!
Post Syndicated from Lennart Poettering original https://0pointer.net/blog/projects/fedora-planet.html
Am I the only one who thinks that the usefulness of Fedora Planet as severely limited
because of the low signal-to-noise ratio that is due to far too many non-english (i.e. german,
french) language posts?
Post Syndicated from Lennart Poettering original https://0pointer.net/blog/projects/pulseaudio-fud.html
If you want to know more about PulseAudio‘s relation to GNOME (especially if
you think PA is evil) then please read through this
thread on desktop-devel, and especially this
long email I posted as a reply a few minutes ago, where I try to debunk all the FUD that has been spread.
Post Syndicated from Lennart Poettering original https://0pointer.net/blog/projects/mango-lassi.html
Yesterday, at the GNOME Summit in Boston I did a quick presentation of my new desktop input sharing
hotness thingy, called “Mango Lassi” (Alternatively known as “GNOME Input Sharing”). Something like a Synergy done right, or an x2x that doesn’t suck.
So, for those who couldn’t attend, here’s a screenshot, which doesn’t really tell how great it is, and which might also be a bit confusing:

And here’s a list of random features already available:
And here’s a list of missing features:
And finally, here’s where you can get it:
git clone http://git.0pointer.de/repos/mango-lassi.git/
Oh, and I don’t take feature wishlist requests for this project. If you need
a feature, implement it yourself. It’s Free Software after all! I’d be happy if
someone would be willing to work on Mango Lassi in a way that it can become a
really good GNOME citizen and maybe even a proper part of it. But personally
I’ll probably only work on it to a level where it does all I need to work with
my Laptop and my Desktop PC on my desk in a sane way. I am almost 100% busy
with PulseAudio these days, and thus
unable to give Mango Lassi the love it could use. So, stand up now, if you want
to take over maintainership!
Hmm, Mango Lassi could use some good artwork, starting with an icon. I am
quite sure that someone with better graphic skills then me could easily create
a delicious icon perhaps featuring a glass of fresh, juicy Mango
Lassi. I’d be very thankful for every icon submission!
Post Syndicated from Lennart Poettering original https://0pointer.net/blog/projects/twenty-first.html
Yours truely, Lennart (C list blogger).