Tag Archives: devops

Investigate DMS migration issues with AWS DevOps Agent

Post Syndicated from Chitresh Saxena original https://aws.amazon.com/blogs/devops/investigate-dms-migration-issues-with-aws-devops-agent/

Migrating a production database is a high-risk operational event. AWS DMS is a cloud service that migrates relational databases, data warehouses, and other data stores into the AWS Cloud or between environments. It moves the rows reliably, but the failures that page an on-call engineer rarely happen during the data copy. They occur in the hours after the cutover. A query that was fast on the old engine starts doing full scans. A connection pool sized for the old database becomes exhausted. A downstream service that nobody mapped begins timing out.

These are operational problems, not data problems. They resolve slowly because engineers must correlate many sources under time pressure: DMS task state, Amazon CloudWatch metrics, Amazon RDS Performance Insights, logs, and deployment history.

AWS DevOps Agent can investigate and troubleshoot your database migration issues. DevOps Agent is your always-available teammate that accelerates and validates the deployment of code changes, then keeps your applications running optimally across AWS, multicloud, and on-prem environments. It learns about your resources and their relationships, then correlates telemetry, code, and deployment data to pinpoint root causes and recommend fixes. When issues arise, it autonomously investigates and resolves them.

In this post, you’ll learn how to extend AWS DevOps Agent into a DMS migration specialist. You deploy a sample Model Context Protocol (MCP) server that gives the agent read-only, migration-specific tools and a library of runbooks. You’ll then watch the agent investigate real migration issues and reach grounded root causes on its own. The accompanying GitHub repository includes the full source and a deployment guide.

Prerequisites

Before you begin, make sure you have the following:

  • An AWS account with AWS DevOps Agent turned on and an Agent Space created. Note the Agent Space ID.
  • An active AWS DMS replication task that migrates to Amazon Aurora PostgreSQL-Compatible Edition, with data validation turned on. The repository includes scripts that provision a test migration if you need one.
  • Permissions to deploy AWS CloudFormation stacks that create AWS Lambda functions, IAM roles, and an S3 bucket.
  • The AWS Command Line Interface (AWS CLI) v2 configured, and Python 3.10 or later. No Node.js or CDK is required.

Architecture

DevOps Agent runs inside AWS. It reaches the MCP server over HTTPS and authenticates each request with AWS Signature Version 4 (SigV4). SigV4 is the same IAM mechanism that every AWS API uses, with no keys or shared secrets. The sample deploys your MCP server onto AWS Lambda, behind a Lambda function URL with the AWS_IAM auth type. That auth type accepts only SigV4-signed requests from authorized principals.

The following diagram shows the request path from the agent to the tools.
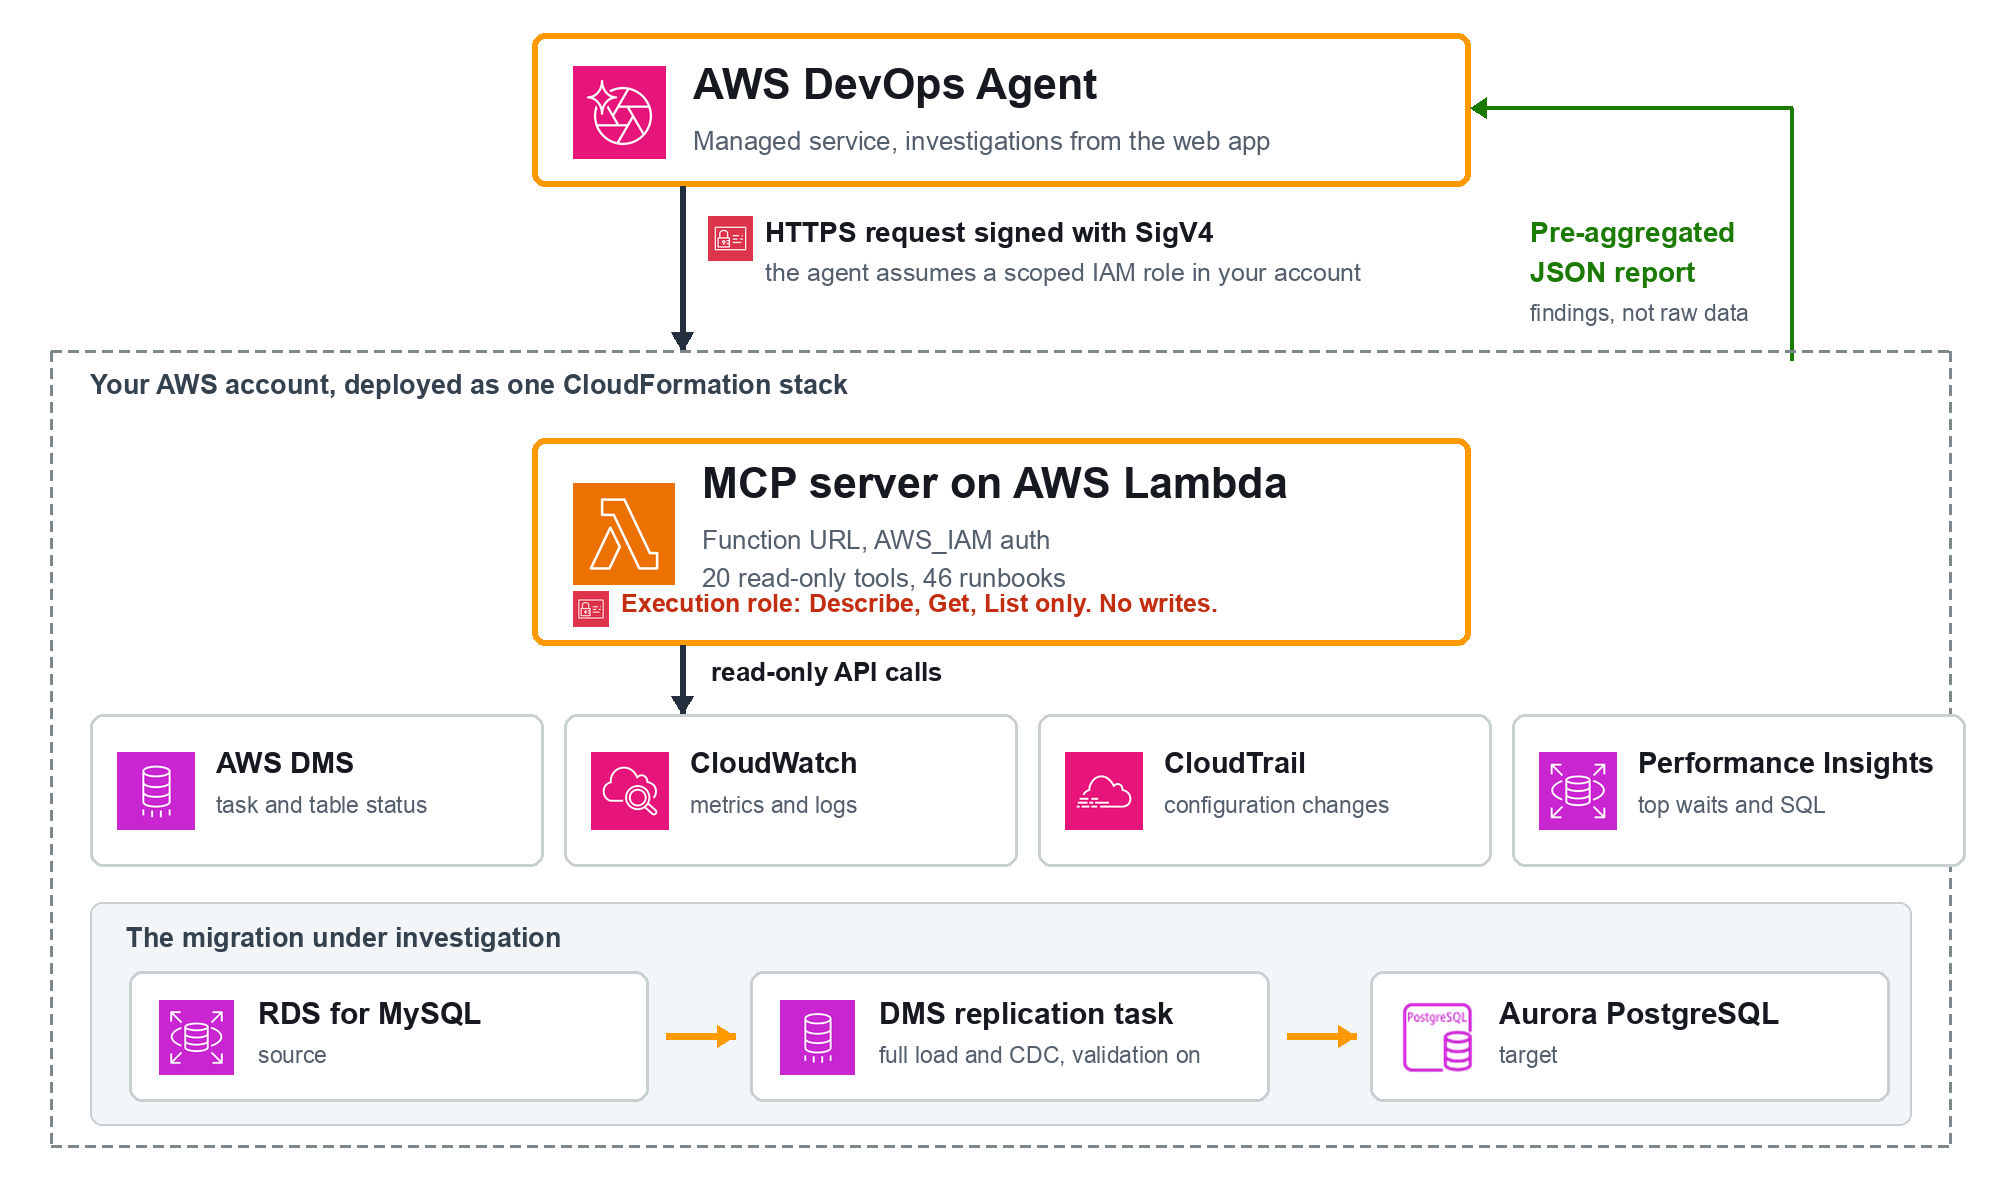
Architecture diagram

You deploy the server and its IAM roles as one AWS CloudFormation stack. You then register the function URL with DevOps Agent and add the tools to the allow list in your Agent Space. When a symptom appears, you create an investigation. The agent assumes the role, calls the tools, correlates the results, and returns the root cause.

Implementation walkthrough

DevOps Agent supports custom tools through MCP. After you deploy the sample server and register it, the agent calls its tools during an investigation, the same way it calls a CloudWatch tool. Every tool in this server calls only Describe*, Get*, List*, Lookup*, and TestConnection APIs. None of them modifies a resource, which is the property that lets you give them to an autonomous agent.

The MCP exposes 20 tools across the migration lifecycle. The following table lists the ones the agent reaches most often.

Tool Returns
validate_migration_data Validation state distribution, failed and suspended tables (report and skill prompt)
get_validation_failures Tables in non-Validated states with failed and suspended record counts
check_connection_health Endpoint connectivity (waits for the real test result), SSL mode, failure messages
analyze_cdc_latency Source vs target CDC latency, backlog, and an assessment
check_replication_instance_health Replication-instance CPU, memory, swap, storage, network with flags
capture_aurora_performance Aurora CloudWatch metrics and Performance Insights waits and SQL
check_stabilization Post-cutover regressions, missing alarms, recommendations (report and skill prompt)
summarize_task_health One-call roll-up across status, validation, latency, and instance health
list_runbooks / get_runbook Browse the runbook catalog and fetch one by id

The server also ships 46 runbooks covering data validation, full load, CDC, connectivity, replication-instance health, Aurora target health, and cutover readiness.

Database migration stages

You can apply this approach across the migration timeline:

  • Pre-cutover readiness: Confirm endpoint connectivity and that every table has reached the Validated state before you commit to the switch.
  • Issue investigation during cutover: You give the agent a symptom, such as a validation mismatch or a latency spike, and it finds the root cause instead of several engineers chasing parallel theories.
  • Post-cutover stabilization: Detect regressions and missing alarms on the new database before they turn into outages.

What the agent sees, and what it does not

Out of the box, DevOps Agent reads Amazon CloudWatch, AWS CloudTrail, and the AWS APIs in your account. However, for a DMS migration, the agent needs to read migration-specific reasoning an operator applies: how to read a DMS validation state distribution, how to tell a source-side change data capture (CDC) bottleneck from a target-side one, or which alarms a freshly promoted Aurora instance should have but it only has access to raw CloudWatch metrics.

You close that gap with the sample MCP server:

  • Read-only tools that turn DMS, CloudWatch, and Performance Insights data into pre-aggregated reports. The tools do the counting deterministically, and the agent does the interpretation.
  • Runbooks the agent can browse and follow, each grounded in public AWS documentation.

Deploy the MCP server

The MCP server runs on AWS Lambda, the serverless compute service that runs your code without provisioning servers. AWS DevOps Agent reaches it through a Lambda function URL, a dedicated HTTPS endpoint for the function. You do not run or host anything yourself; the deployment creates the Lambda function and its endpoint in your account.

The endpoint is not open to the public. It uses the AWS_IAM auth type, so it accepts only requests that DevOps Agent signs with an IAM role in your account, as described in the architecture section above.

Deploying and registering are two distinct steps. Deploying creates the server: the Lambda function, the function URL, and the IAM roles. Registering tells DevOps Agent that the server exists and adds its tools to the allow list. You can select either of the two options as indicated below.

Option A: Deploy MCP and register via AWS Management Console

Deploy the MCP and perform the MCP registration manually via console:

./deploy.sh us-east-1 --skip-register

The script deploys the MCP server and prints its Function URL and role ARN, then leaves the registration to you. With the server deployed, register it in the console by following Connecting MCP servers:

  1. Sign in to the AWS Management Console and open the AWS DevOps Agent console.
  2. On the Capability Providers page, find MCP Server under Available providers and choose Register.
  3. On the MCP server details page, enter a Name, the Endpoint URL (the function URL from the stack output), and an optional Description.
  4. For the authorization method, choose AWS SigV4, enter the role ARN from the stack output, set the Region to us-east-1, and set the service name to lambda.
  5. Open your Agent Space, go to the Capabilities tab, and add the tools to the allow list.

Option B: Deploy MCP and register with one click deployment

Alternatively, you can deploy the MCP and perform the MCP registration with one-click deployment. Complete the following steps to deploy and register the server.

  1. Clone the repository and change to the deployment directory:
git clone https://github.com/aws-samples/sample-dms-devops-mcp.git
cd sample-dms-devops-mcp/lambda_mcp
  1. Run the deployment script with your target Region:
./deploy.sh us-east-1

The script prompts for your Agent Space ID. It then packages the Lambda code, deploys the CloudFormation stack, and registers the server with your Agent Space, allow-listing all of its read-only tools.

  1. Verify the deployment. In the DevOps Agent console, open your Agent Space, go to the Capabilities tab, and confirm the tools appear under MCP Servers.

If registration returns HTTP 403, confirm the IAM role grants both lambda:InvokeFunctionUrl and lambda:InvokeFunction. Granting only the first returns 403. The template grants both.

Review and investigation

To validate the approach, we ran it against a live migration: an Amazon Relational Database Service (Amazon RDS) for MySQL source replicating to Aurora PostgreSQL through a DMS task with data validation turned on, 1,000 rows across four tables (customers, products, orders, and order_items). Every query and response below is from a real DevOps Agent investigation against that environment. You start each one by entering a prompt in the DevOps Agent web app, the conversational interface where you investigate issues and review findings.

A consistent pattern shows up across all five investigations: the agent chooses a different set of tools for each question. It is reasoning about which tool fits, not running a fixed script.

The five scenarios are not demo picks. Each one represents a class in the DMS failure taxonomy the server’s 46 runbooks cover: data validation, full load, change data capture, connectivity, replication-instance health, Aurora target health, and cutover readiness. That taxonomy is the operational surface of a real migration, so a reader who follows these five is rehearsing the categories they are most likely to hit, not a curated happy path. Each scenario below is one representative of its class; the full catalog is available to the agent through list_runbooks.

Pre-Migration: Confirm cutover readiness

Before a cutover, you want a clear go or no-go.

Query

We are about to cut over the DMS migration (task dms-mcp-test-task, us-east-1, target Aurora dms-mcp-test-target). Before we switch the application, confirm whether this migration is ready: are the endpoints healthy and has all data validated? Give me a clear go or no-go.

Response

The agent chose exactly the go/no-go gate tools: check_connection_health and validate_migration_data for the readiness signals, plus get_task_status, get_validation_failures, list_table_statistics, and analyze_cdc_latency to confirm the full picture. The connection-health tool waits for the real endpoint test result rather than reporting that a test merely started, and the validation tool confirms whether DMS actually compared source and target rows and found them equal, not just that the full load reached 100 percent. In our test runs the agent returned this go/no-go in under two minutes, against the fifteen to thirty minutes an operator typically spends cross-checking endpoint tests, task status, and per-table validation state by hand. (Illustrative from our runs, not a benchmark.)
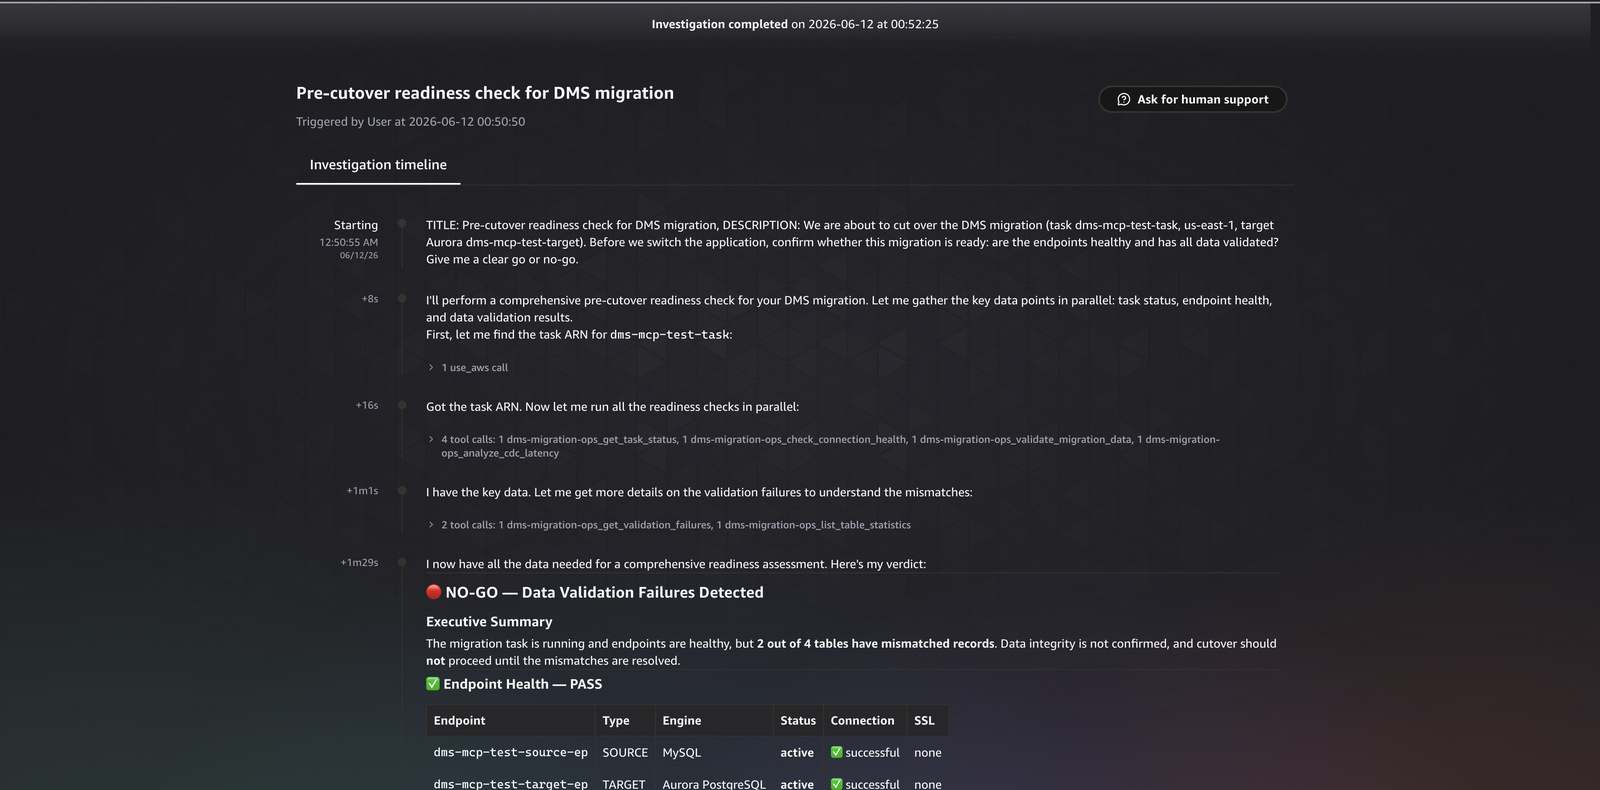
Cutover readiness check

Figure 1. The readiness check, showing endpoint health and validation state feeding a go/no-go assessment.

Migration: Investigate validation failures

To create a fault, we changed two rows directly on the Aurora target, bypassing DMS, which moved the customers and orders tables to the Mismatched records state.

Query

Our DMS migration to Aurora PostgreSQL (task dms-mcp-test-task in us-east-1, Aurora instance dms-mcp-test-target) is reporting data validation failures on some tables. Investigate the root cause and tell me how to fix it.

Response

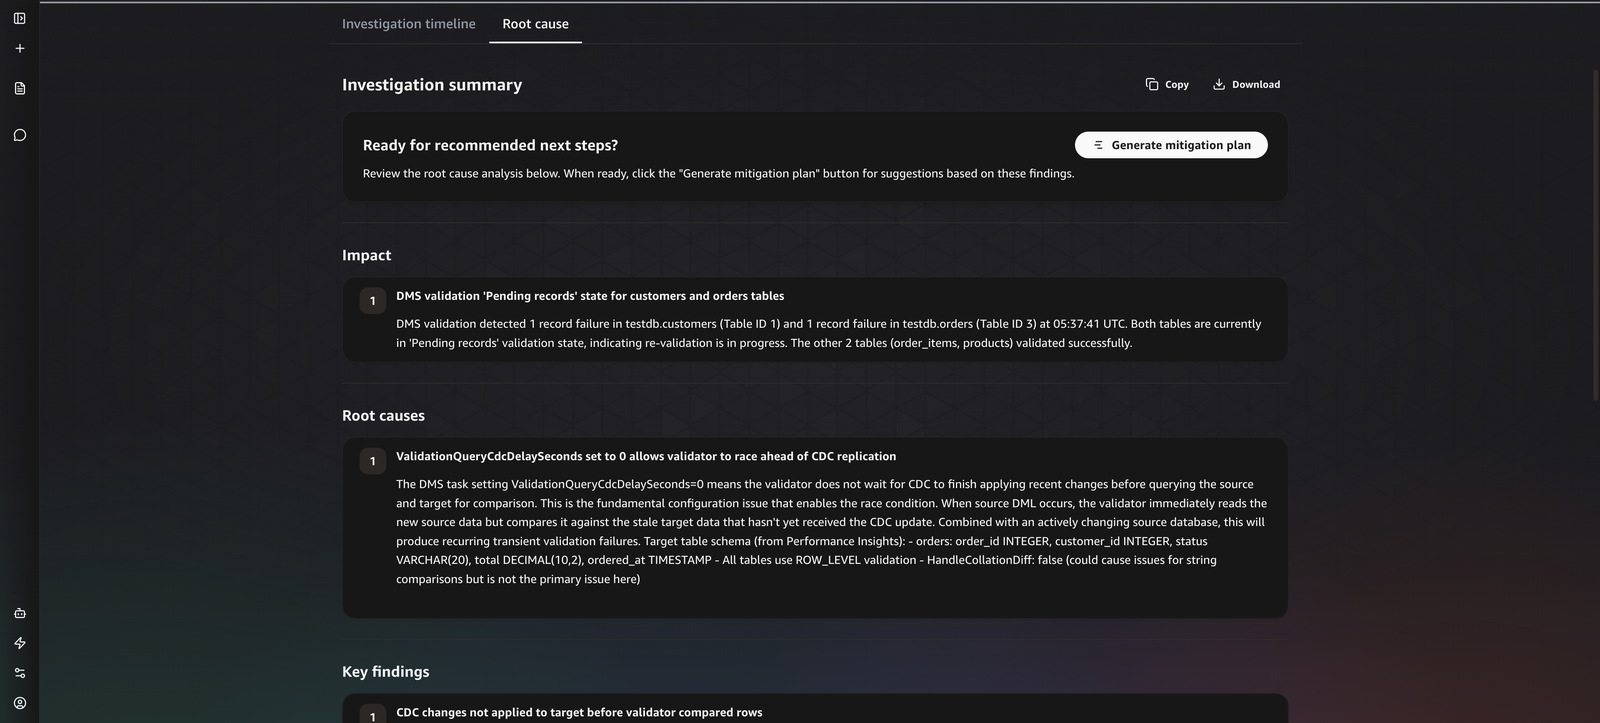
The agent ran a deep investigation across 73 journal records, calling 11 of the registered tools (33 tool calls in total). It started with get_task_status, get_validation_failures, validate_migration_data, and list_table_statistics to establish which tables had diverged, then used search_task_logs, correlate_cloudtrail_changes, get_recent_task_events, analyze_cdc_latency, capture_aurora_performance, describe_endpoints, and get_premigration_assessment to build the timeline. It identified both affected tables and produced these findings:

 Finding: CDC changes not applied to target before validator compared rows
 Source modifications occurred on customers and orders at ~05:37:18 UTC.
 The validator compared at 05:37:41 UTC, 23 seconds later, before CDC applied
 them to Aurora. Evidence: CDC captured 17 source events but target id was 0
 (no changes applied), and TARGET_APPLY logs showed "waiting for data from
 upstream" through the window.
 Finding: ValidationQueryCdcDelaySeconds set to 0 allows the validator to race
 ahead of  CDC replication.

That second finding is the difference between a dashboard and an investigation. The agent did not just report which tables failed. It named the exact DMS task setting (ValidationQueryCdcDelaySeconds) behind the transient failures and explained the mechanism, which is the fix an operator can act on. In our test runs the agent reached the ValidationQueryCdcDelaySeconds root cause in a single investigation of about three minutes, work that manually means correlating the failure table, CDC latency, CloudTrail, and task logs across four consoles, commonly thirty minutes or more. (Illustrative from our runs, not a benchmark.)
Validation failure investigation

Figure 2. The DevOps Agent investigation for the validation failure, showing the tool timeline and the root-cause findings.

Migration: Assess replication latency

During ongoing replication, you want to know whether CDC is keeping up and where any delay sits.

Query

I want to understand the replication performance of our DMS task dms-mcp-test-task in us-east-1. Is the change data capture keeping up, and is the replication instance healthy or is it a bottleneck? Summarize the latency picture.

Response

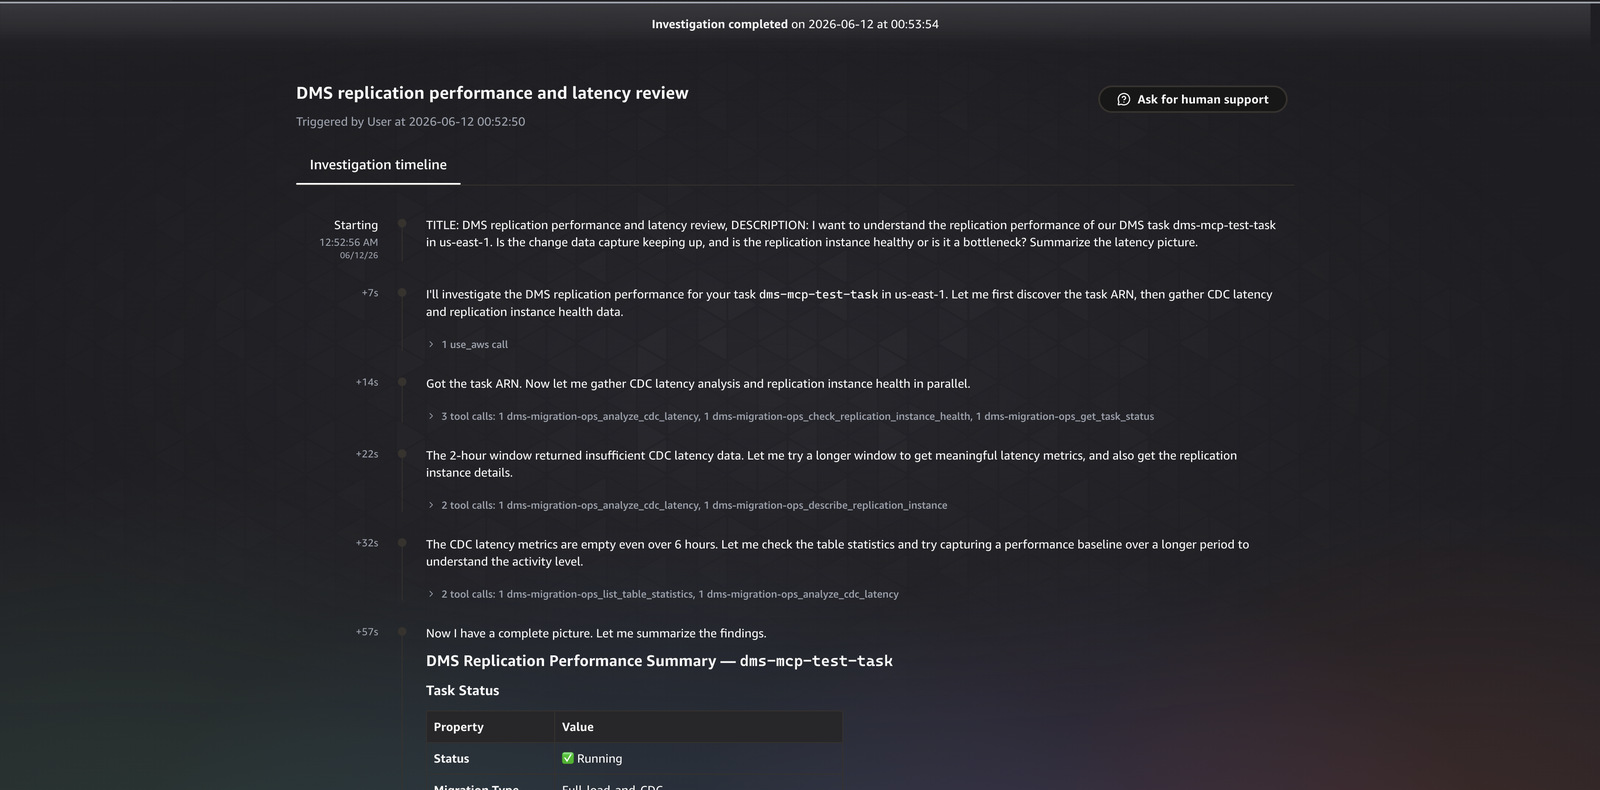
The agent picked up the performance-specific tools: analyze_cdc_latency, check_replication_instance_health, and describe_replication_instance, with get_task_status and list_table_statistics for context. The latency tool compares source latency with target latency and returns an assessment, because the two together tell you where the delay sits. When source and target latency track each other, the bottleneck is the source side. When target latency runs well above source latency, the bottleneck is the target apply side. The instance-health tool flags CPU, memory, swap, and storage pressure that would make the instance itself the limit. In our test runs the latency assessment came back in roughly a minute, versus the manual path of pulling source and target CDC latency and instance metrics from CloudWatch and reasoning about which side leads. (Illustrative from our runs, not a benchmark.)

The latency tool also knows when it cannot answer. When the metric window is too sparse to separate source-side from target-side delay, it returns an insufficient_data verdict and asks for a longer window instead of forcing a conclusion from a handful of datapoints. This is deliberate: a confident but wrong root cause is worse than a request for more data. The agent surfaces that verdict to you rather than inventing a bottleneck, which is what makes its confident answers trustworthy when it does give them.
Replication latency assessment

Figure 3. The replication latency assessment, comparing source and target CDC latency and instance health.

Migration: Run an open-ended investigation

Sometimes the operator does not know what is wrong yet. This is where the runbooks earn their place.

Query

Something seems off with our DMS migration (task dms-mcp-test-task, us-east-1, Aurora target dms-mcp-test-target) but I am not sure what. Investigate broadly, use any available runbooks that match what you find, and report the most important issue with how to fix it.

Response

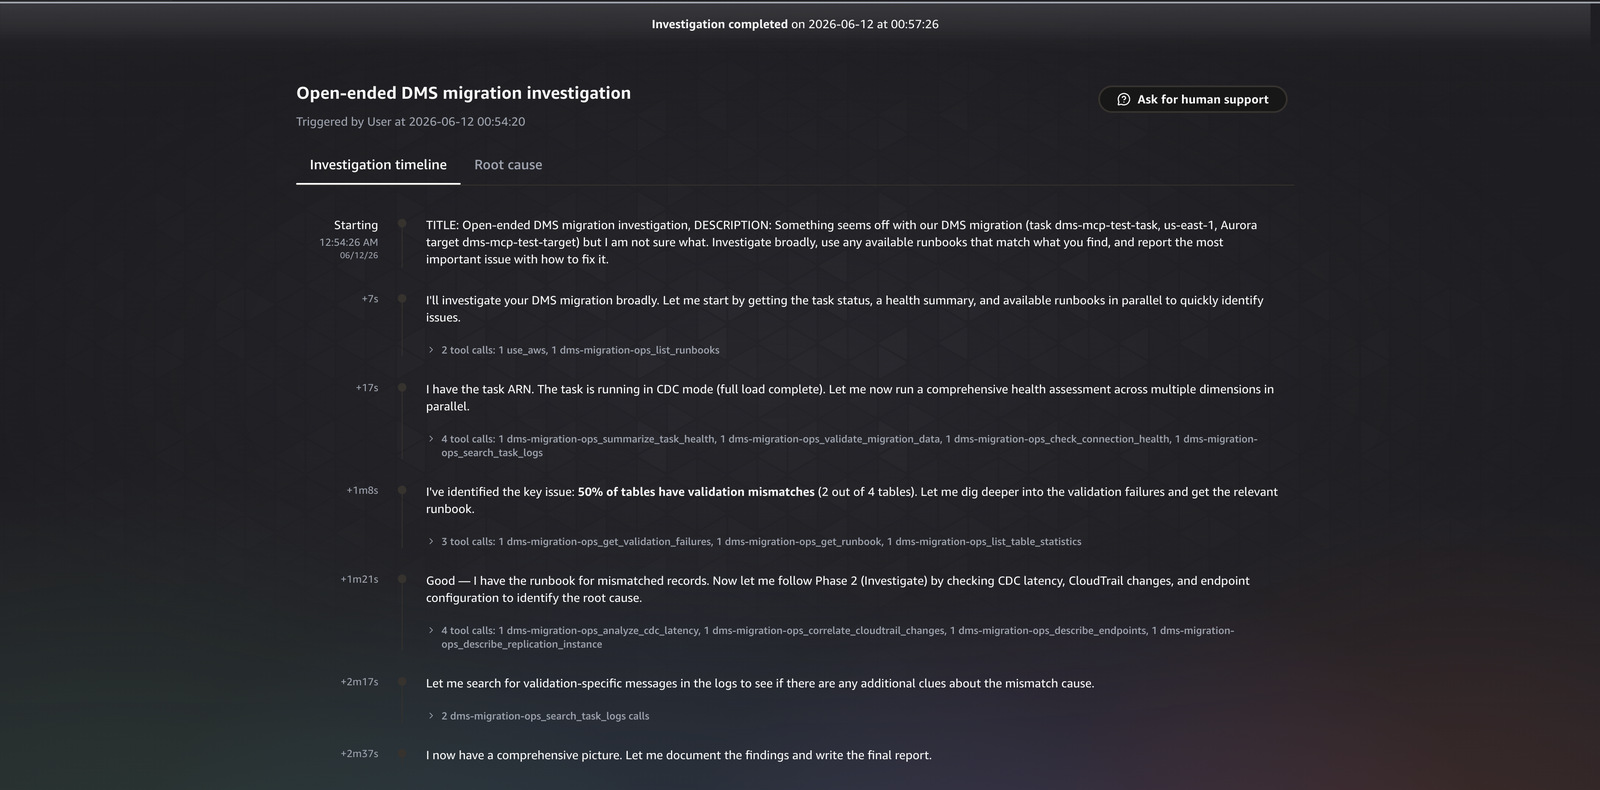
Given no specific symptom, the agent ran the broadest investigation of the suite: 12 distinct tools across 43 records. It swept the task status, validation state, connectivity, latency, replication instance, endpoints, and logs, then called list_runbooks, recognized the validation symptom it had found, and fetched get_runbook for the matching runbook, which returned the full procedure. It produced a finding about a datatype or precision difference in the MySQL to PostgreSQL migration and followed the runbook to the recommended remediation. In our test runs this broad sweep of twelve tools resolved to a single prioritized finding in a few minutes, against the open-ended manual triage it replaces, which has no fixed time because the operator does not yet know where to look. (Illustrative from our runs, not a benchmark.)

Tools the agent chose: validate_migration_data, get_validation_failures,
list_table_statistics, check_connection_health, describe_endpoints,
describe_replication_instance, analyze_cdc_latency, summarize_task_health,
search_task_logs, correlate_cloudtrail_changes, list_runbooks, get_runbook
Open-ended investigation

Figure 4. The open-ended investigation, showing the agent browse the runbook catalog and follow the matching runbook.

Post-Migration: Review stabilization and monitoring

After cutover, the question shifts from “did the data move” to “is the new database healthy and watched.”

Query

We just cut over to Aurora PostgreSQL (instance dms-mcp-test-target) from a DMS migration (task dms-mcp-test-task, us-east-1). Assess the target database health now and tell me what monitoring or alarms are missing that we should add before production traffic ramps up.

Response

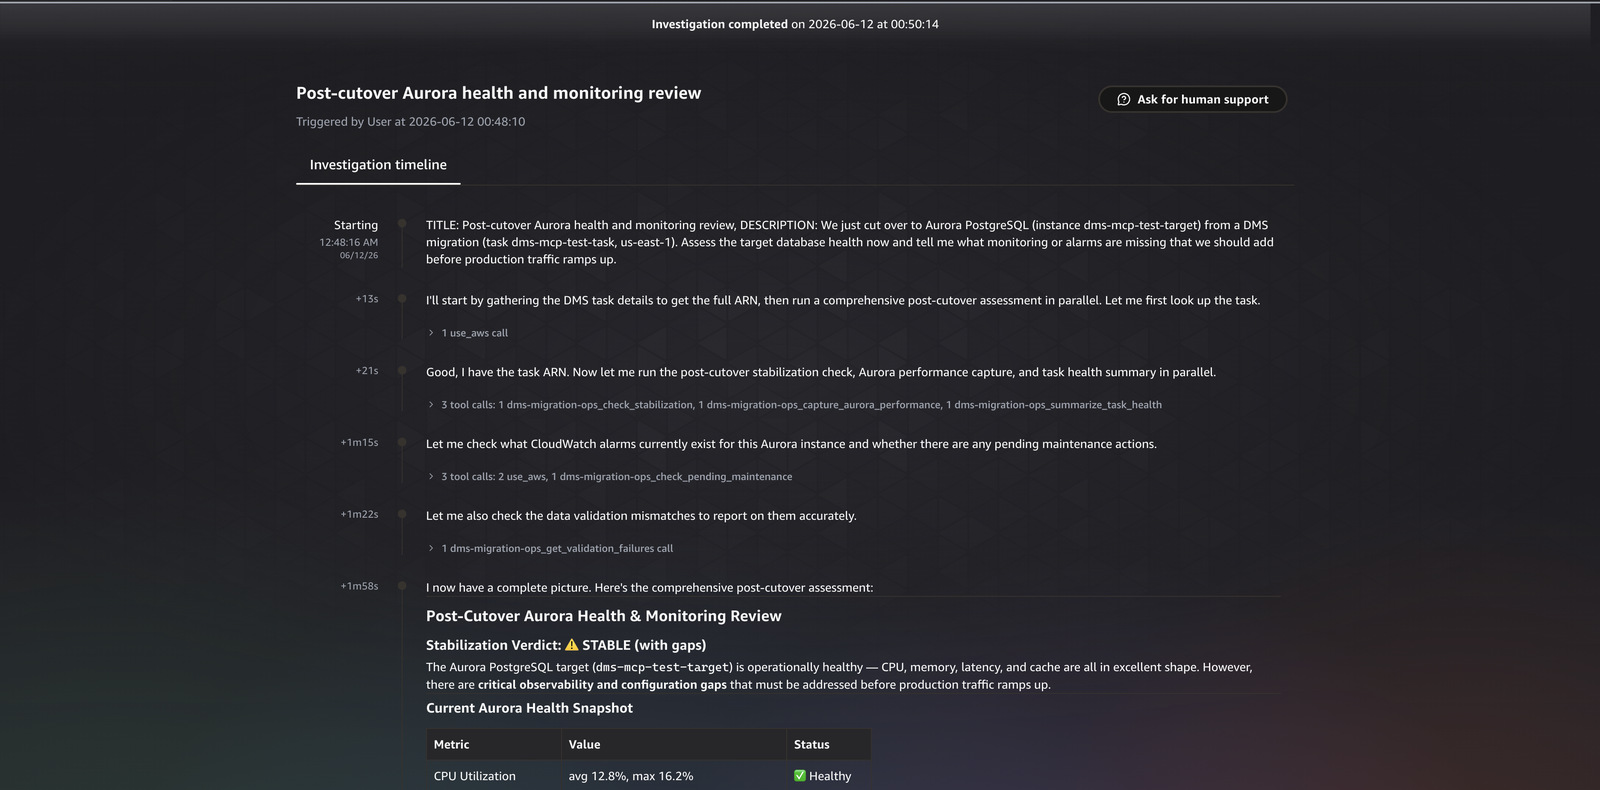
The agent selected the stabilization tool set: check_stabilization, capture_aurora_performance, summarize_task_health, get_validation_failures, and check_pending_maintenance. It read the Aurora target health (CPU, connections, read and write latency, buffer cache hit ratio, and the top Performance Insights wait event), then assessed what monitoring was missing for a database about to take production traffic. The point of this phase is the interpretation: a buffer cache hit ratio that stays low after warmup points to missing indexes, and a new database with no alarm on connection count or query latency is one bad query away from an unmonitored outage. In our test runs the stabilization review returned target health and the specific missing alarms in about two minutes, versus manually inspecting Aurora metrics and Performance Insights and then deciding which alarms a freshly promoted database still lacks. (Illustrative from our runs, not a benchmark.)
Post-cutover stabilization review

Figure 5. The post-cutover stabilization review, with target health and the monitoring gaps the agent flagged.

Improve the agent with Skills and runbooks

A finding like the ValidationQueryCdcDelaySeconds race condition should improve the next migration, not be relearned. The agent’s migration judgment is captured in two places. DevOps Agent Skills are Markdown instruction sets that load automatically when relevant and tell the agent when to call a tool and how to read its output. The runbooks are fetched on demand: the agent calls list_runbooks to browse the catalog, then get_runbook to pull the procedure that matches what it found, as it did in scenario 5. You can fold each new finding back into a skill or runbook, so the agent improves with every migration.

To make the flywheel concrete, here is the runbook the agent fetched in the open-ended investigation. When it found the validation symptom, it called get_runbook and received this procedure, authored from earlier findings and grounded in public AWS documentation:

---
id: validation-mismatched-records
title: "Validation: mismatched records on a table"
severity: HIGH
triggers:
  - "ValidationState=Mismatched records"
  - "ValidationFailedRecords>0"
tools:
  - get_validation_failures
  - list_table_statistics
  - analyze_cdc_latency
  - correlate_cloudtrail_changes
---

# Validation: mismatched records on a table

A table shows Mismatched records, meaning source and target rows differ.
The row-level diffs are recorded in the awsdms_validation_failures_v1
control table on the target.

## Phase 1 — Assess
- Run get_validation_failures to see which tables are in Mismatched records
  and the failed-record counts.
- Run list_table_statistics to confirm the per-table validation state.

## Phase 2 — Investigate
- Query awsdms_validation_failures_v1 on the target for the failing rows/columns.
- Run analyze_cdc_latency: if validation runs during heavy CDC, transient
  diffs can appear while changes are in flight.
- Run correlate_cloudtrail_changes to check for an out-of-band write or reload.
- Check for data-type, precision, timezone, or character-set differences.

## Phase 3 — Report
- State which tables diverged and by how many records.
- Name the most likely cause (type/precision, timezone, encoding, out-of-band write).
- Recommend revalidating the table after the cause is corrected.

## Remediation (operator action)
- Correct the underlying difference, then revalidate with validate-only.

> All steps use read-only MCP tools. Remediation actions are operator tasks
> and are not performed by the tools.

The judgment for when to apply a runbook lives in a DevOps Agent Skill, a Markdown instruction set that loads automatically when relevant. The data-validation skill, for example, encodes the rules the agent follows before it draws a conclusion:

# Skill: DMS Data Validation Assessment

## Critical Rules
- Every finding MUST cite actual numbers from the metrics report, never generalize.
- Do NOT fabricate or estimate any metric. If data is missing, say "Data not available."
- Do NOT hardcode thresholds, use relative comparisons (% of total, trend direction).
- Validation metrics come from TWO sources: the DMS table-statistics API AND
  CloudWatch. Cross-reference both.

## Concepts to Evaluate — ValidationState machine
- Validated          = healthy, all rows confirmed matching
- Mismatched records = ACTION REQUIRED, source/target differ, check failure table
- Suspended records  = source churn too high, DMS cannot compare
- No primary key     = CANNOT VALIDATE, table lacks a PK
Flag if Mismatched + Suspended + Error tables exceed 5% of the total.

Every new finding folds back into a runbook or a skill, so the next migration starts from what the last one learned. The ValidationQueryCdcDelaySeconds race condition from scenario 2 becomes a trigger the agent recognizes on sight, rather than something it has to rediscover.

When to use this approach

This pattern fits issue investigation, pre-cutover readiness gates, and post-cutover stabilization reviews, where an operator hands the agent a symptom and wants a grounded root cause from read-only tools. It is not a replacement for continuous monitoring or alarms, and it does not ship logs for long-term retention. Use it alongside your existing CloudWatch alarms and dashboards, not instead of them.

Clean up

To avoid ongoing charges, delete the resources you created. Delete the CloudFormation stack with aws cloudformation delete-stack --stack-name dms-mcp-test-mcp-server. Remove the MCP server from your Agent Space and deregister it. If you provisioned a test migration with the repository scripts, run the included cleanup script.

Conclusion

Migration issues usually stem from operational problems, not data problems, and AWS DMS does not catch them. In this post, you saw how to extend AWS DevOps Agent to investigate them autonomously, using a sample MCP server that exposes read-only, migration-specific tools and runbooks. Across five real investigations, the agent chose the right tools for each question, found the affected tables, named the exact task setting behind a validation race condition, and followed a runbook to a fix. Because the tools are read-only and access is least-privilege IAM, you can give them to an autonomous agent without widening your operational scope.

To get started, deploy the MCP server from the GitHub repository, register it with your Agent Space, and turn on DMS data validation before your next cutover.

About the authors

Chitresh Saxena

Chitresh Saxena
Chitresh Saxena is a Senior AI/ML Specialist, specializing in generative AI solutions and dedicated to helping customers successfully adopt AI/ML on AWS. He excels at understanding customer needs and provides technical guidance to build, launch, and scale AI solutions that solve complex business problems.

Neel Sendas

Neel Sendas
Neel Sendas is a Principal Technical Account Manager at AWS, leading Cloud Operations for some of AWS’s largest enterprise customers across ML governance, cloud finance, and operational resilience at scale. He is also a core member of AWS’s Machine Learning Technical Field Community, helping shape the roadmap for AWS AI/ML services.

Tipu Qureshi

Tipu Qureshi
Tipu Qureshi is a Senior Principal Technologist in AWS Agentic AI, focusing on operational excellence and incident response automation. He works with AWS customers to design resilient, observable cloud applications and autonomous operational systems.


Automating the Experimentation Lifecycle with Kiro, AWS DevOps Agent, and LaunchDarkly

Post Syndicated from Greg Eppel original https://aws.amazon.com/blogs/devops/automating-the-experimentation-lifecycle-with-kiro-aws-devops-agent-and-launchdarkly/

Introduction

Continuous improvement depends on experimentation. Teams know that the fastest path to better outcomes is to test changes against real user behavior, measure results, and iterate. In practice, sustaining that cycle is slow and costly because the overhead compounds with each attempt.

Three barriers slow teams down:

1. Planning cost — Turning a proposed change into a testable experiment requires defining a feature flag strategy, coordinating implementation, and wiring everything together before any user sees new behavior.

2. Measurement disconnected from action — Once live, teams must configure metrics, define success criteria, monitor, and interpret results. When metrics regress, remediation traditionally depends on a human merging a fix or rolling back a deployment.

3. Stalled iteration — Without a record of which change caused which outcome, the next hypothesis is a guess, so iteration often does not happen and the goal stalls.

This post introduces a reference solution that closes the gap between defining a goal and reaching it. A team states an improvement goal (for example, increase add-to-cart rate by 10%), and agents plan the experiment, implement the change, deploy it behind a feature flag, measure its impact, and iterate on the result, all within defined safety boundaries. The solution connects Kiro for code generation, AWS DevOps Agent for orchestration and release readiness review, and LaunchDarkly for feature flag governance, experiments, and Guarded Releases for safe, metric-driven rollouts with automatic rollback. The architecture described here is a reference implementation you can build today. A more turnkey experience is planned for the future.

Pre-requisites

Step 1. Enable AWS DevOps Agent and Create an Agent Space. AWS DevOps Agent is available in the AWS regions listed here. Follow these steps to create your AWS DevOps Agent and create an Agent Space.

Step 2. Create your LaunchDarkly account. Create your LaunchDarkly account using the AWS Marketplace or through LaunchDarkly website.

Step 3. Enable the LaunchDarkly MCP Server in the Agent Space. AWS DevOps Agent connects to LaunchDarkly’s hosted MCP server as a client, giving it the ability to query flag state, read targeting rules, and list flags by project or environment.

Step 4 — Register the LaunchDarkly MCP server (account-level). MCP servers are registered at the AWS account level and shared among all Agent Spaces in that account.

  • Sign in to the AWS DevOps Agent console.
  • Navigate to the Capability Providers page (side navigation).
  • Find MCP Server under the Available providers section and choose Register.
  • Enter the MCP server details (see table below).
  • Choose Next.
    • Name: LaunchDarkly
    • Endpoint URL: https://mcp.launchdarkly.com/mcp/launchdarkly
    • Description: LaunchDarkly feature flag management MCP server
    • Enable Dynamic Client Registration: Select this checkbox to allow DevOps Agent to automatically register with LaunchDarkly’s authorization server

Step 4a — Configure the authorization flow

LaunchDarkly’s hosted MCP server uses OAuth for authentication:

  • Select OAuth 3LO (Three-Legged OAuth).
  • Choose Next.
  • Complete the OAuth authorization — you will be redirected to LaunchDarkly’s consent page to authorize the connection.
  • Choose Next.
  • Tip: Refer to the LaunchDarkly MCP server documentation for specific OAuth scope and credential details.

Step 4b — Review and submit

  • Review the MCP server configuration details.
  • Choose Submit.
  • AWS DevOps Agent validates the connection to LaunchDarkly’s MCP server.
  • On successful validation, the MCP server is registered at the account level.

Step 5 — Add the MCP server to your Agent Space

After the account-level registration, connect it to your specific Agent Space:

  • In the AWS DevOps Agent console, select your Agent Space (created in Section 1).
  • Go to the Capabilities tab.
  • In the MCP Servers section, choose Add.
  • Select the LaunchDarkly MCP server you just registered.
  • Configure tool access:
    • Allow all tools — makes all LaunchDarkly MCP tools available to the agent
    • Select specific tools — allowlist only the tools you need (recommended for production)
  • Choose Add.

Step 5 — Validate the connection. Run a test query to confirm the integration is working. In the DevOps Agent console, start a new investigation or chat session and ask: “List the feature flags in the <your-project-key> project in the production environment.” If the agent returns flag data from LaunchDarkly, the connection is active.

Solution overview

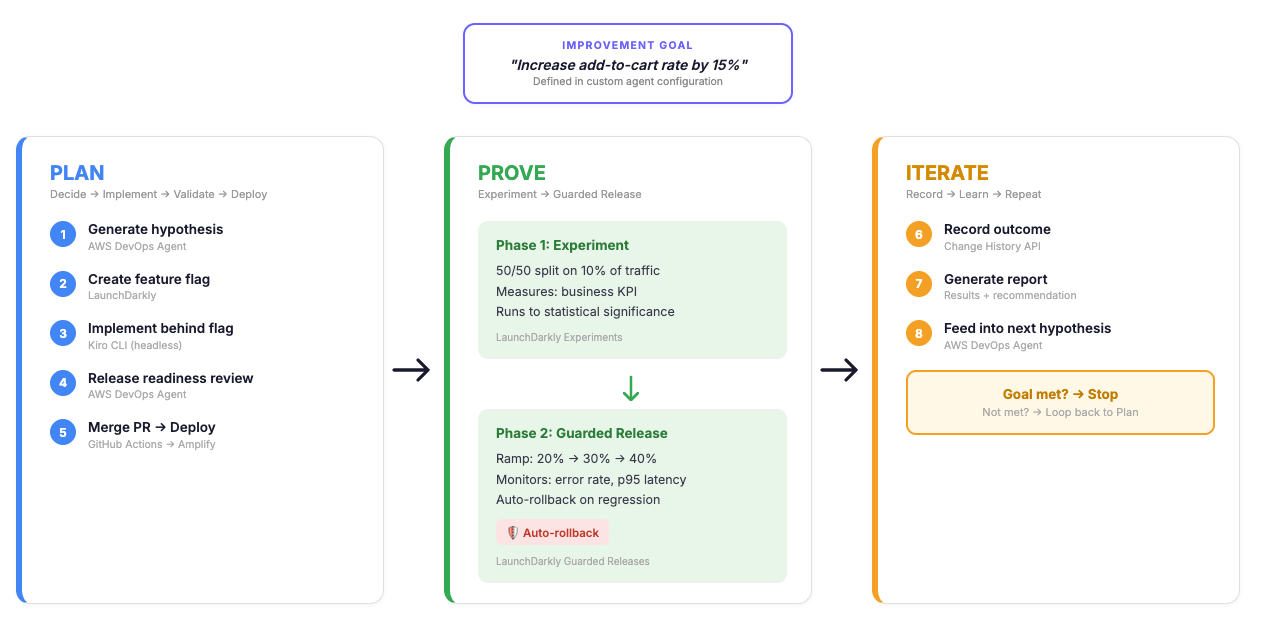
The automated experimentation lifecycle operates as a closed loop. A team states an improvement goal, and the system moves through a continuous cycle: decide what to try next, implement the change behind a feature flag, validate and deploy it, run an experiment to measure impact, roll it out safely, and feed the outcome back into the next iteration. The loop continues until the goal is met or the team decides to stop.

Flowchart showing the Plan-Prove-Iterate continuous improvement loop for AWS DevOps Agent. The Plan phase covers steps 1 through 5: generate hypothesis, create feature flag, implement behind flag, release readiness review, and merge PR to deploy. The Prove phase has two sub-phases: Experiment (50/50 split on 10% traffic measuring business KPIs) and Guarded Release (ramp from 20% to 40% with auto-rollback on regression). The Iterate phase covers steps 6 through 8: record outcome, generate report, and feed into next hypothesis, ending with a goal-met decision gate. An improvement goal banner reads "Increase add-to-cart rate by 15%."

End-to-end Plan-Prove-Iterate workflow showing how AWS DevOps Agent orchestrates hypothesis generation, feature-flagged implementation, experimentation, guarded rollout, and outcome recording in a continuous improvement loop.

Each component has a distinct responsibility. AWS DevOps Agent orchestrates the cycle: it runs on a schedule as a Custom Agent which is a user-defined agent with its own instructions, skills, and connected tools that executes autonomously without pausing for input unless something fails. AWS DevOps Agent supports Custom Agents as a way to encode a specific workflow, including its decision logic, safety constraints, and cadence, into an agent that runs end-to-end on its own. In this solution, the Custom Agent reviews goals, generates hypotheses informed by prior outcomes, coordinates implementation and validation, and drives iteration across multiple experiment cycles.”. Kiro CLI runs in headless mode inside the Experiment MCP Server container on Amazon Bedrock AgentCore, implementing code changes behind LaunchDarkly feature flags and opening pull requests without a human operating an IDE.

LaunchDarkly hosts feature flags, experiments, and Guarded Releases, monitors metrics in real time, and reverts flag state when a threshold is breached. It also exposes a hosted MCP server with tools the agent calls directly. The Experiment MCP Server (custom, built for this solution) exposes the remaining operations over MCP: code implementation through Kiro, PR merge, and deployment triggering.

The agent acts as an MCP client connected to these two servers. LaunchDarkly’s hosted MCP server provides flag management, experiment lifecycle, Guarded Release, and observability tools. The Experiment MCP Server provides code implementation, PR merging, and deployment tools. This design separates decision-making from execution: the agent decides what to do, the MCP servers handle how.

Plan / Prove / Iterate

The lifecycle operates in three phases.

Plan — The agent decides the next action for a goal, generates a hypothesis informed by prior outcomes when iterating, and creates a feature flag in LaunchDarkly. It then invokes Kiro CLI to implement the change behind the flag and open a pull request. AWS DevOps Agent validates the change through release readiness review. After a green review, the PR is merged and a GitHub Actions workflow deploys the application through AWS Amplify.

Prove — Two sequential phases run after deployment. First, a 50/50 experiment splits 10% of traffic on a business KPI (for example, add-to-cart rate) until statistical significance selects a winning variation. Then a Guarded Release ramps the winning variation from 20% to 30% to 40% and eventually to 100% while LaunchDarkly monitors operational guardrails (error rate, page-load-time-p95). If a guardrail threshold is breached, LaunchDarkly reverts the flag state automatically, requiring no redeployment. The experiment measures value (does the change improve the goal metric?); the Guarded Release measures safety (does the change hold up at scale?).

Iterate — After a rollout concludes, the agent queries LaunchDarkly’s Change History API to associate specific flag modifications with outcomes. The recorded outcome informs the next hypothesis, and the cycle repeats until the goal is met or the agent recommends waiting.

Extending the agent with a custom MCP server

AWS DevOps Agent reads code, reviews changes, and decides what to do next. It does not take action on its own. To move from decision to execution, you connect it to MCP servers that expose operations as tools.

LaunchDarkly’s hosted MCP server covers flags, experiments, and Guarded Releases. We needed operations it doesn’t cover — writing code, merging PRs, and deploying — so we built the Experiment MCP Server. It runs on Amazon Bedrock AgentCore and exposes five tools: create_task and get_task_status (invoke Kiro CLI to implement changes and open a PR), merge_pr, trigger_deployment, and get_deployment_status.

These are mutation operations. When the agent calls create_task, Kiro writes real code. When it calls merge_pr, that code lands in main. You are responsible for this server — what it exposes, which repos it can touch, which branches it can merge to. We scoped ours to one repository, one branch, and one Amplify application. Those constraints live in the MCP server’s code, not the agent’s prompt, because API-level scoping cannot be misinterpreted.

The Experiment MCP Server [CG1] is a Python application built on FastMCP, packaged as a container and deployed to Amazon Bedrock AgentCore over stateless HTTP so the platform can restart or replace the container without breaking in-flight requests. At startup, the container pulls credentials from AWS Secrets Manager, clones the target repository, and makes Kiro CLI available as a local binary. This single-container design keeps everything colocated: when the agent calls create_task, the server spawns Kiro CLI as a headless subprocess with direct filesystem access to the cloned repo rather than making a network call to a separate code-generation service. Kiro CLI receives a structured prompt containing the task description, the LaunchDarkly flag key, and the variation details, then writes the change, commits to a new branch, and pushes. The server opens a pull request through the GitHub API and returns the task ID immediately without waiting for Kiro to finish. The caller polls get_task_status, which long-polls against an S3-backed state store so task progress survives container restarts. Deployment tracking follows a similar pattern: trigger_deployment dispatches a GitHub Actions workflow and returns the real GitHub run ID, and get_deployment_status reads live status directly from GitHub, so there is nothing to lose if the container cycles between calls. The overall design principle is that the MCP server coordinates work and delegates persistence to external systems (S3 for task state, GitHub for deployment state, Secrets Manager for credentials) rather than holding anything in memory that a restart would erase.

How the agent works

The agent runs on a schedule. Each run, it evaluates the current state of each goal and picks one of three actions: create a new experiment (no active rollout exists), iterate on a prior result (a rollout completed and the goal is not yet met), or wait (an experiment or rollout is still in progress).

The entry point for the system is an outcome, not a task list. The team picks a business metric from the available set — add-to-cart rate, checkout conversion, bounce rate, or page-load-time-p95 — and sets a target improvement, for example “increase add-to-cart rate by 10%.” Error rate is reserved as a safety guardrail during the Guarded Release phase and cannot be chosen as the primary success metric, because the system needs an independent operational signal to decide whether a winning variation is safe to scale. Beyond the metric and the target, all other inputs are optional. The agent infers the current baseline, the areas of the application in scope for changes, and any constraints from the codebase and production data. If those assumptions are off, the team corrects them before any code is written. The team states where they want to end up, and the agent works backward from there.

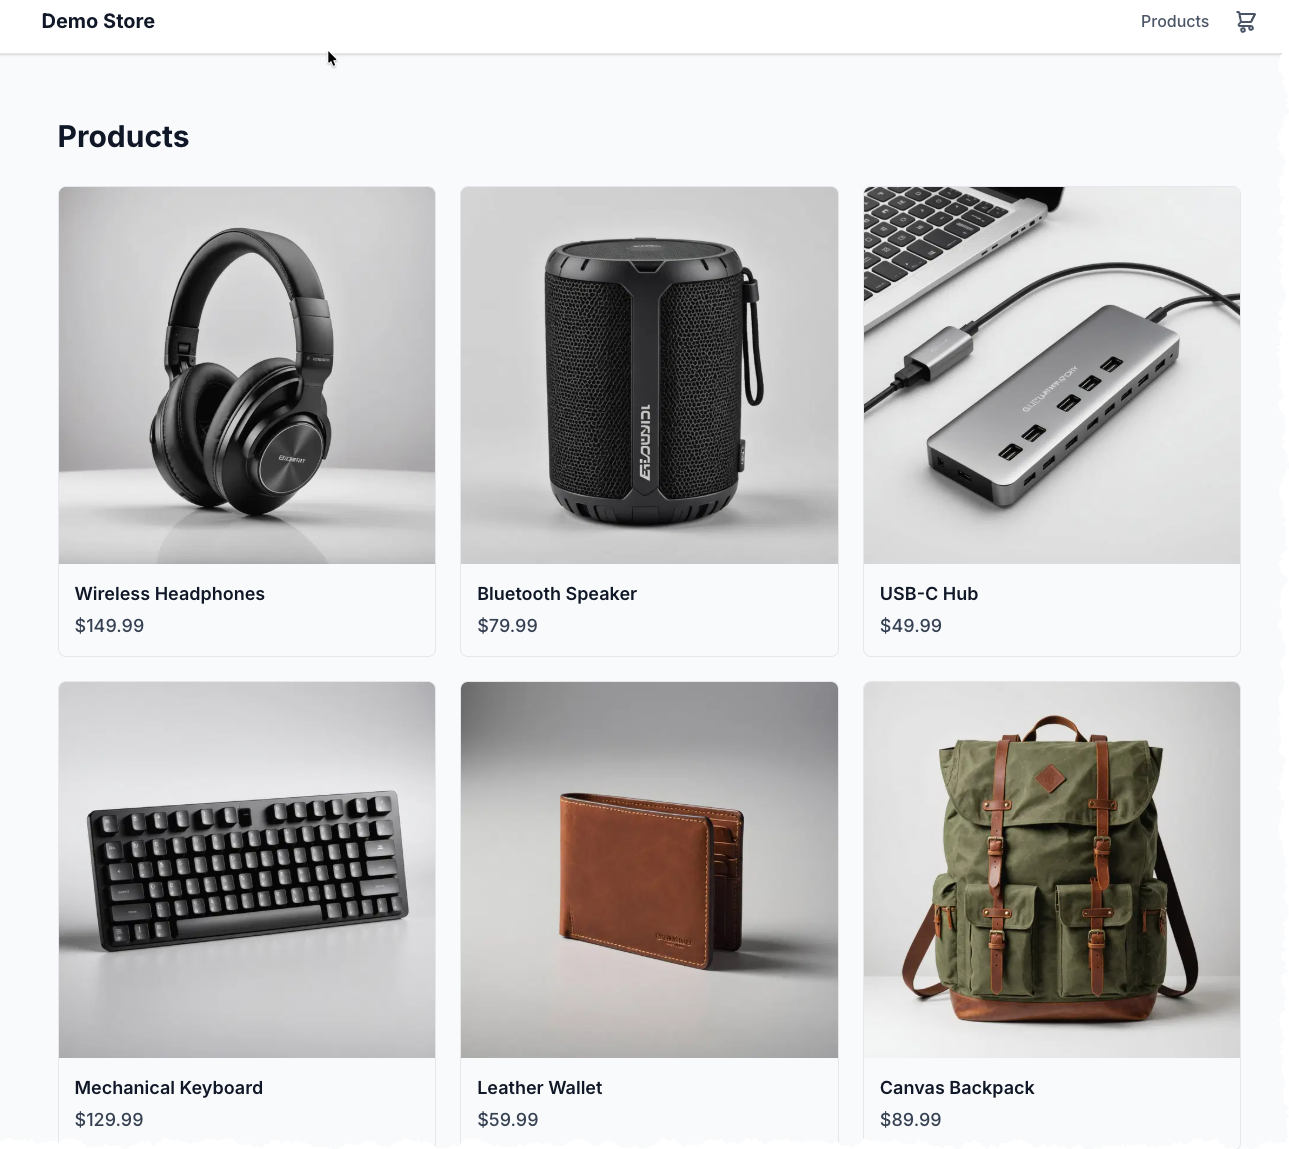
Ecommerce demo store product listing page showing a grid of six products: Wireless Headphones at $149.99, Bluetooth Speaker at $79.99, USB-C Hub at $49.99, Mechanical Keyboard at $129.99, Leather Wallet at $59.99, and Canvas Backpack at $89.99. Each product card displays a product photo with name and price below. The page header shows "Demo Store" with Products and cart navigation links.

Demo Store product listing page used as the test surface for the add-to-cart experimentation cycles. Product cards currently show the control layout (no inline Add to Cart button).

For new goals, the agent explores the target repository and proposes a code change likely to move the metric. For iterations, it reads prior outcomes and adjusts its approach based on what worked and what did not. Before any code change, the agent creates a feature flag in LaunchDarkly (boolean, OFF by default, named with a convention like exp-add-to-cart-*) so every change ships behind a flag from the start.

Implementation runs through Kiro CLI in headless mode. The agent calls create_task, Kiro clones the repository, writes the change behind the feature flag, and opens a pull request.

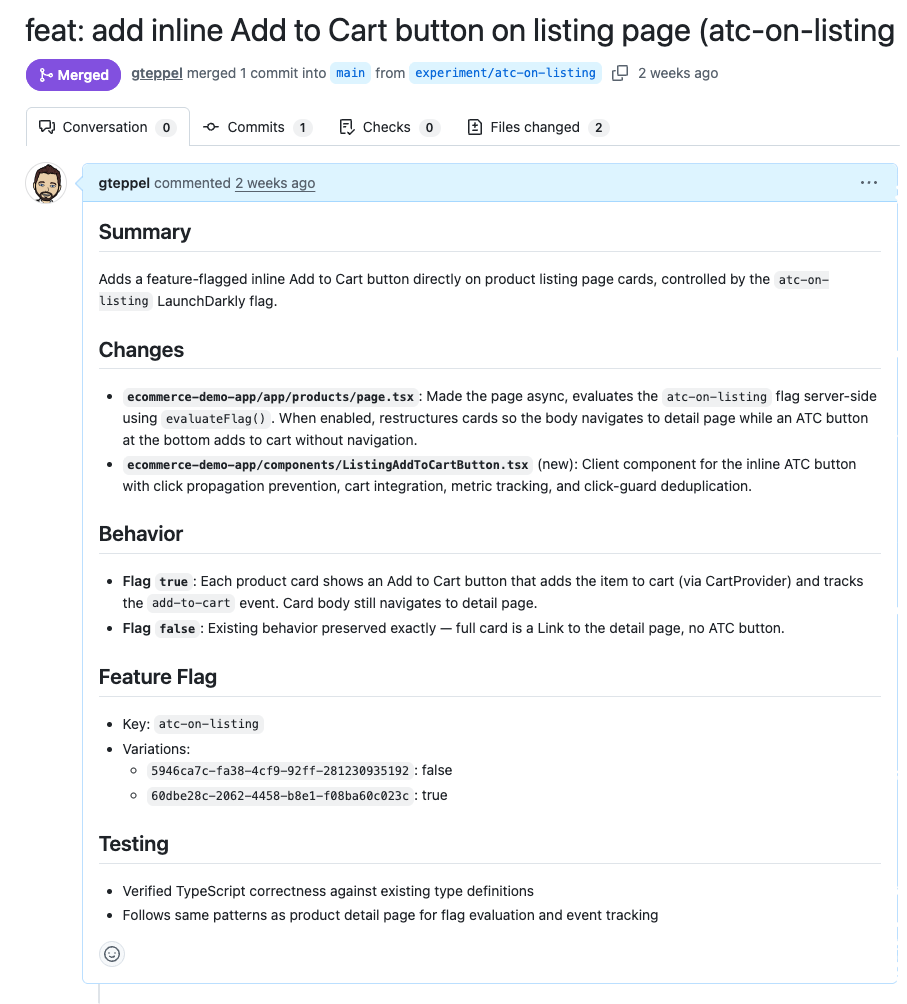
GitHub merged pull request titled "feat: add inline Add to Cart button on listing page (atc-on-listing)" by gteppel. The PR merged 1 commit into main from experiment/atc-on-listing with 2 files changed. The description lists changes to page.tsx and a new ListingAddToCartButton.tsx component, explains flag-true and flag-false behavior, documents the atc-on-listing feature flag key with two variations, and notes TypeScript verification.

Merged GitHub PR implementing the feature-flagged inline Add to Cart button on the product listing page, controlled by the atc-on-listing LaunchDarkly flag.

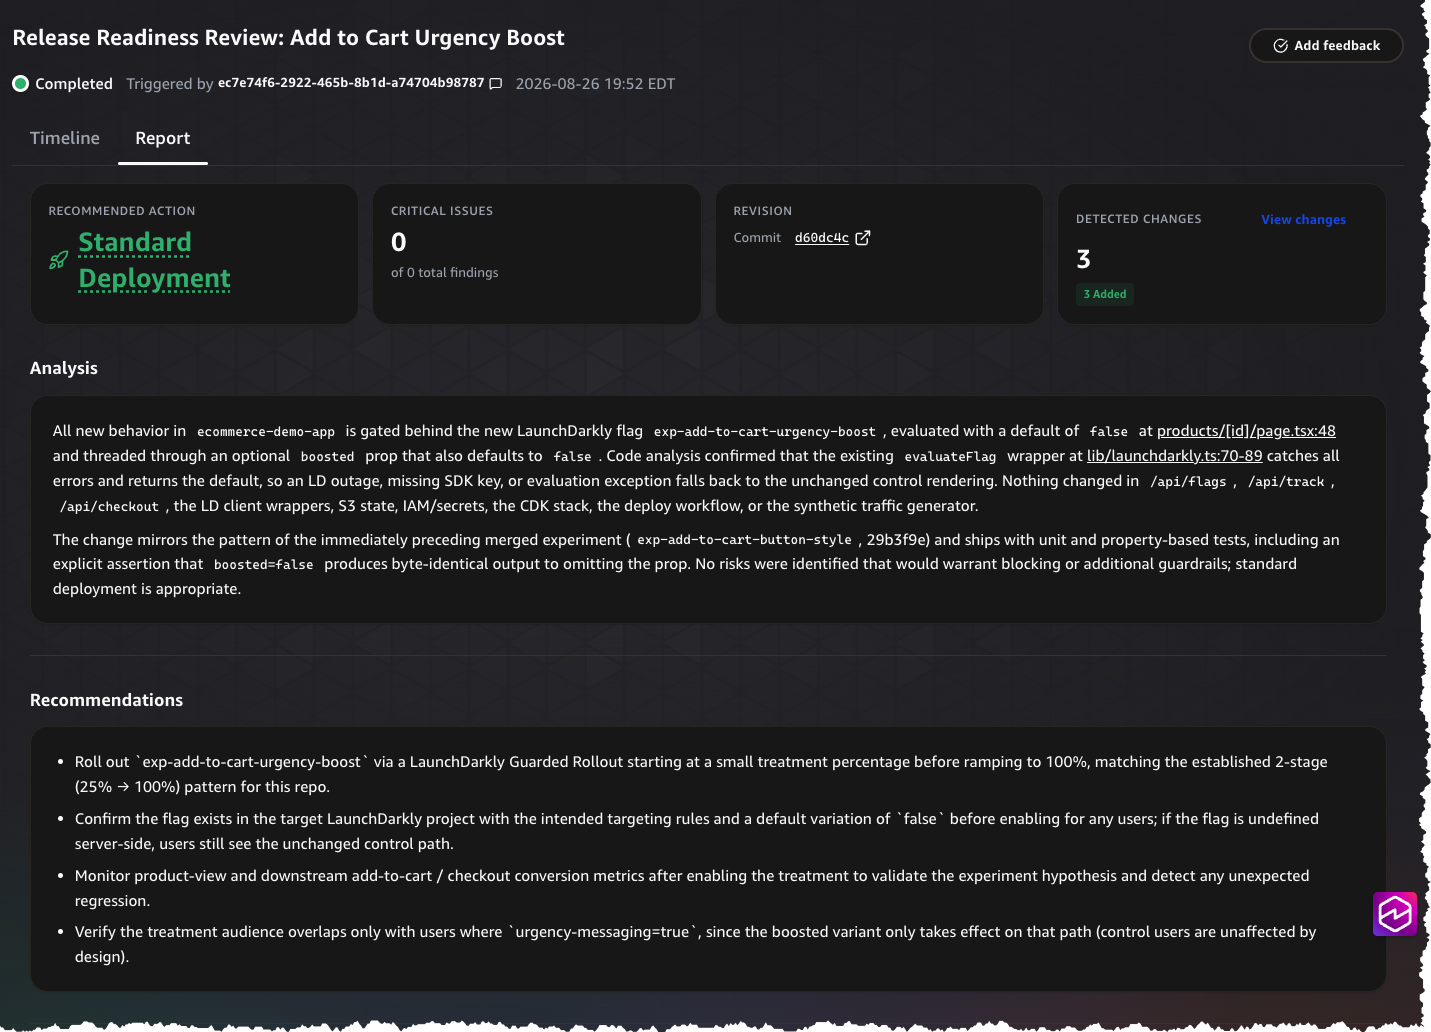
AWS DevOps Agent then runs a release readiness review on the PR. If the review fails, the agent retries up to three times before stopping to ask for help. After a green review, the PR is merged and a GitHub Actions workflow deploys through AWS Amplify.

AWS DevOps Agent Release Readiness Review report for "Add to Cart Urgency Boost," completed on August 26, 2026. The report shows a recommended action of Standard Deployment, zero critical issues, commit d60dc4c, and 3 detected changes (all additions). The analysis section confirms all new behavior is gated behind the LaunchDarkly flag exp-add-to-cart-urgency-boost with a safe default of false. Recommendations include guarded rollout starting at a small treatment percentage, confirming the flag exists in LaunchDarkly, monitoring add-to-cart and checkout conversion metrics, and verifying treatment audience overlap.

AWS DevOps Agent Release Readiness Review for the Add to Cart Urgency Boost experiment. The automated review found zero critical issues and recommended standard deployment with a guarded rollout.

Proving the change

Once deployed, the flag is toggled on and the experiment begins. The agent creates a 50/50 experiment across 10% of traffic, splitting on the goal’s business KPI. In production, experiment data comes from real users interacting with your application, with metrics emitted through OpenTelemetry to LaunchDarkly. For this reference implementation, we built a synthetic traffic generator that simulates user sessions across both treatment and control variations, producing the conversion events and operational metrics that drive experiment decisions. It runs alongside the demo application and generates enough volume to reach statistical significance within minutes rather than days. The synthetic traffic generator is a demo convenience, not a production requirement. Any application that emits the right events to LaunchDarkly will work with this architecture.

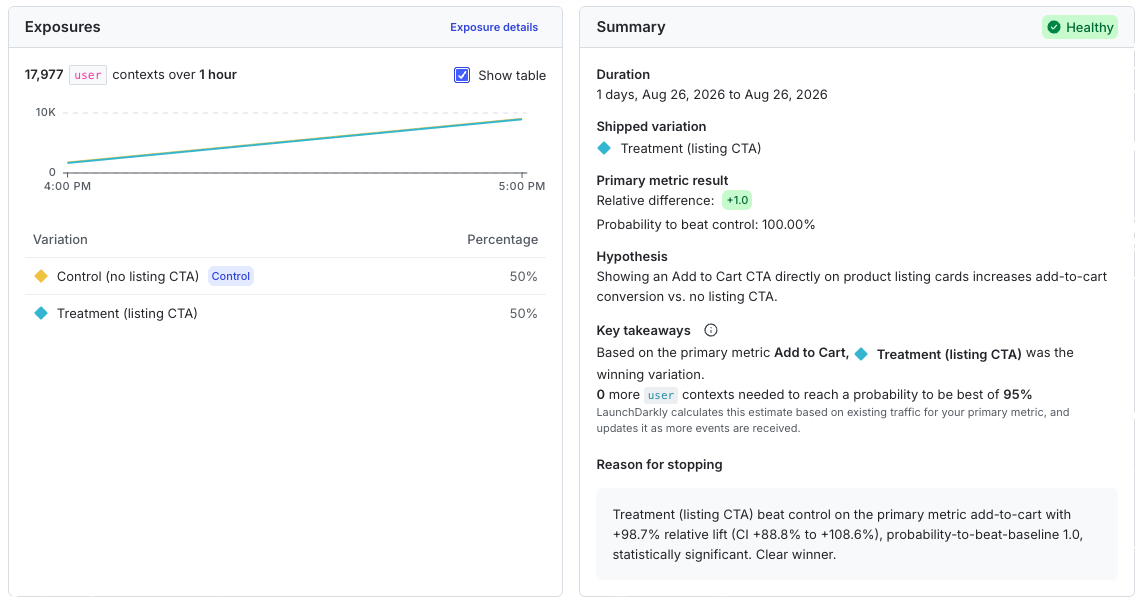
The agent checks for results on each Custom Agent execution until statistical significance is reached. In an interactive chat session, you prompt the agent to check when you are ready. If the treatment wins, the agent proceeds to the Guarded Release. If it loses, the agent archives the flag and records the outcome for the next iteration.

LaunchDarkly experiment results dashboard showing Exposures and Summary panels. Exposures panel shows 17,977 user contexts over 1 hour with a 50/50 split between Control (no listing CTA) and Treatment (listing CTA). Summary panel shows a Healthy status, 1-day duration on August 26 2026, Treatment shipped as the winning variation with a relative difference of plus 1.0 and 100% probability to beat control. The experiment was stopped because Treatment beat control with plus 98.7% relative lift, statistically significant.

LaunchDarkly experiment summary for the inline Add to Cart listing CTA test. Treatment won decisively with 98.7% relative lift in add-to-cart conversion and 100% probability to beat control.

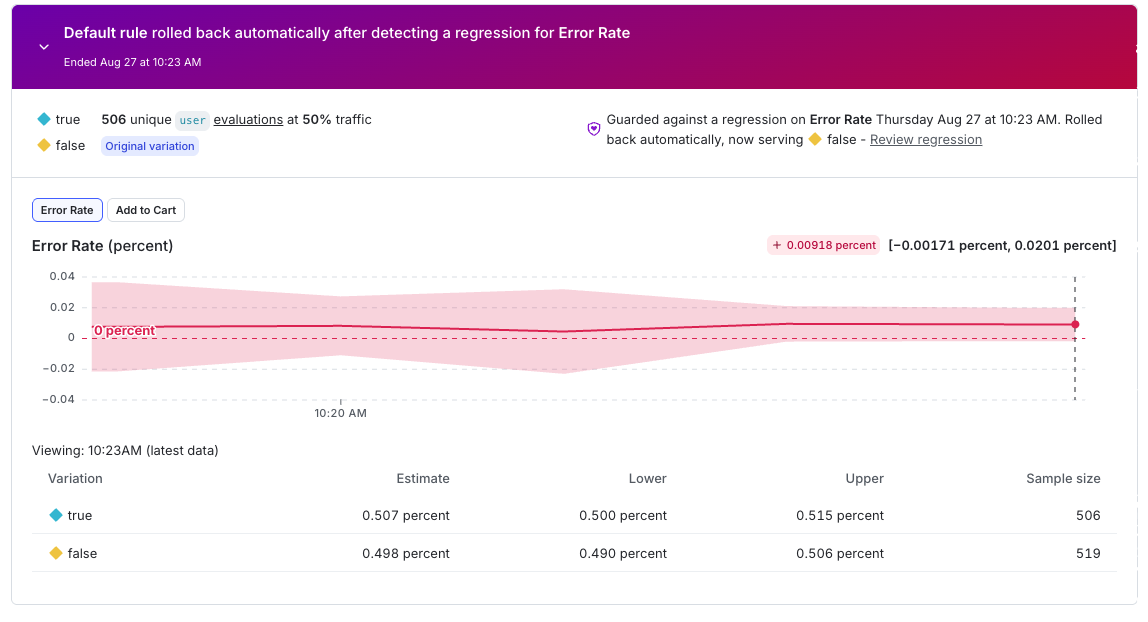
The Guarded Release ramps the winning variation from 20% to 30% to 40% while LaunchDarkly [1] applies sequential testing to the operational guardrail metric, halting the rollout as soon as the data shows a statistically significant regression against the original variation.. If a guardrail threshold is breached at any stage, LaunchDarkly reverts flag state at runtime without a redeployment. Guarded Releases and automatic rollback serve as the runtime safety net: if something goes wrong after deployment, the system reverts flag state without waiting for a human to intervene.

To validate the safety net in the reference implementation, we triggered a simulated error-rate spike during the ramp. LaunchDarkly detected the regression within the monitoring window, halted the rollout, and reverted the flag to its pre-rollout state automatically. No human intervened, no redeployment ran, and the application returned to the control behavior within seconds. The screenshot below shows the Guarded Release dashboard after the rollback.

LaunchDarkly Guarded Release dashboard showing an automatic rollback triggered by an error rate regression. A red banner states the default rule rolled back automatically after detecting a regression for Error Rate, ended August 27 at 10:23 AM. The error rate chart shows the treatment (true) variation at 0.507% versus control (false) at 0.498% with a sample size of approximately 500 per variation. The system rolled back to serving the false variation.

LaunchDarkly Guarded Release auto-rollback event. The system detected an error rate regression during the ramp phase and automatically rolled traffic back to the control variation.

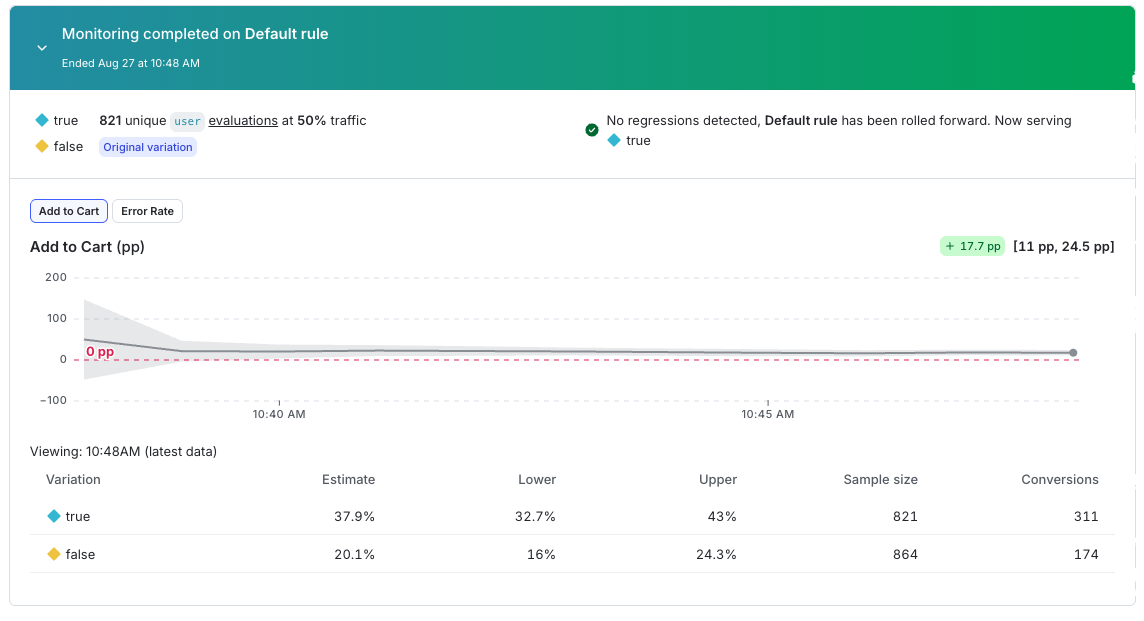
After recording the rollback and feeding the outcome into the next iteration, the agent adjusted its approach and proposed a revised implementation that avoided the latency regression. The second attempt followed the same pipeline: hypothesis, feature flag, implementation, review, deployment, experiment, and Guarded Release. This time, monitoring completed with no regressions detected. LaunchDarkly rolled the winning variation forward to full traffic, with add-to-cart conversion lifting from 20.1% to 37.9% across the treatment population, confirming the experiment result held at scale.

LaunchDarkly Guarded Release dashboard showing successful monitoring completion. A green banner states monitoring completed on the default rule, ended August 27 at 10:48 AM. The Add to Cart metric chart shows the treatment (true) variation at 37.9% conversion versus control (false) at 20.1%, a lift of plus 17.7 percentage points. No regressions were detected, and the default rule rolled forward to serve the true variation. Sample sizes are 821 (true) and 864 (false).

LaunchDarkly Guarded Release monitoring completion. The Add to Cart metric showed a 17.7 percentage point lift with no regressions, so the system graduated the treatment to 100% of traffic.

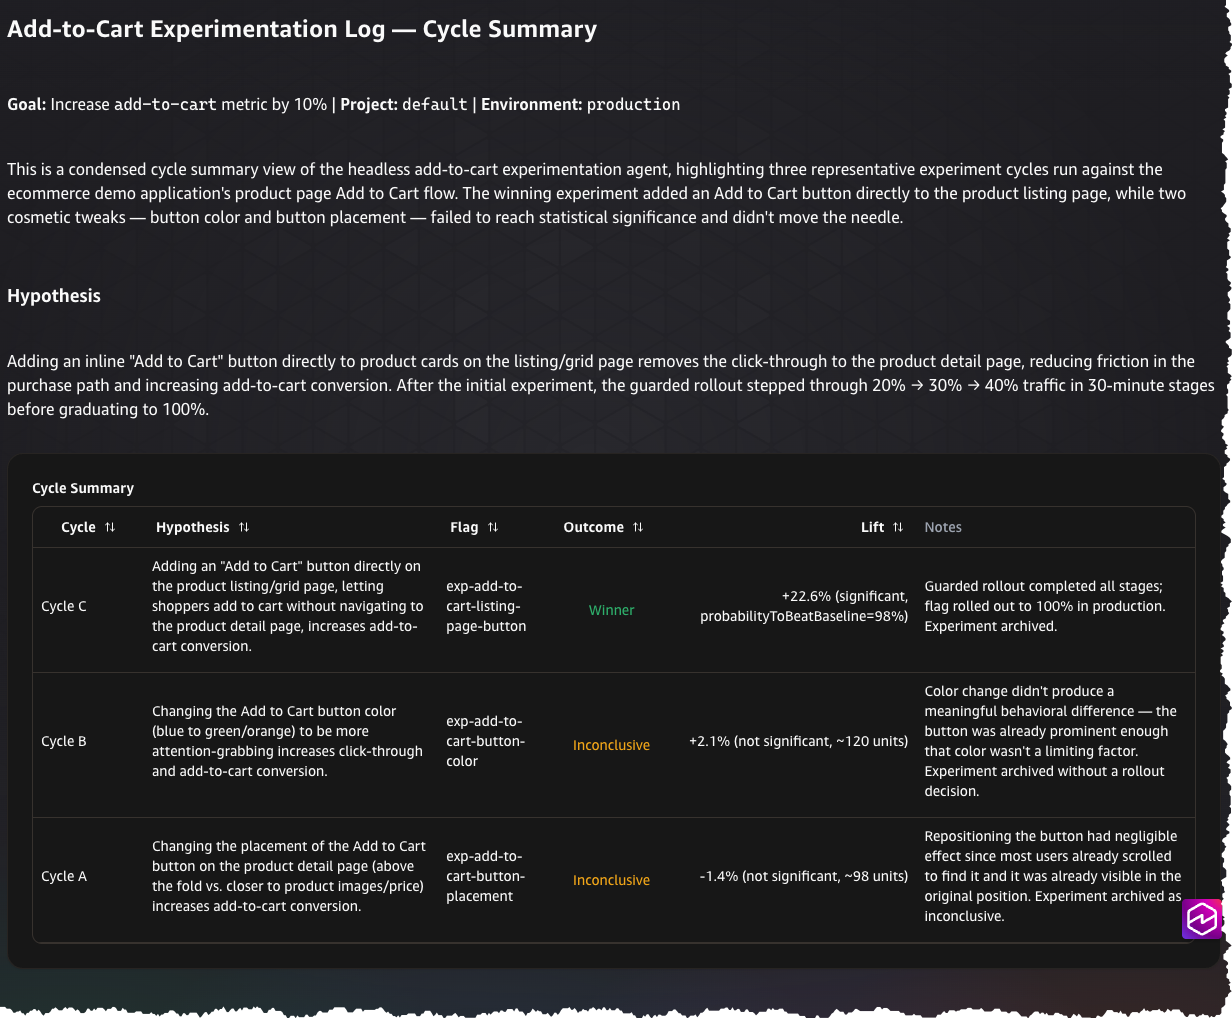
After each cycle, the agent generates a report documenting the hypothesis, experiment results, rollout outcome, and a recommendation for the next iteration. This report feeds into the next decision, so no context is lost between cycles.

Add-to-Cart Experimentation Log showing a cycle summary table with three experiment cycles. Goal is to increase the add-to-cart metric by 10% in the default project and production environment. Cycle C tested adding an Add to Cart button directly to the listing page, resulted in a Winner outcome with plus 22.6% lift (significant, probability to beat baseline 98%), and was rolled out to 100%. Cycle B tested changing the button color from blue to green/orange, resulted in Inconclusive with plus 2.1% lift (not significant, approximately 120 units). Cycle A tested changing button placement on the detail page, resulted in Inconclusive with minus 1.4% lift (not significant, approximately 98 units).

Experimentation cycle summary showing three hypothesis-test iterations. Only Cycle C (inline Add to Cart on listing page) reached statistical significance and was promoted to production. The two cosmetic experiments (button color and placement) were inconclusive.

Safety boundaries

The system operates within defined constraints. The agent validates every change through release readiness review before merge. It creates a feature flag before writing any code, so every change can be toggled off without a redeployment. Guarded Releases enforce operational guardrails at runtime with automatic rollback. The agent retries failed validations up to three times, then stops and asks for help rather than proceeding. All credentials are stored in AWS Secrets Manager and referenced by name only, never exposed in agent logs or tool calls.

Getting started

To implement this workflow, you need AWS DevOps Agent enabled in your AWS account, a LaunchDarkly account (start with a free 30-day AWS trial), and a target application and repository. The reference uses a Next.js app deployed through AWS Amplify. Experiments are available on every LaunchDarkly plan, including the free Developer plan. Guarded Releases, which automate progressive rollouts with automatic rollback, require a LaunchDarkly Enterprise plan with the Guardian add-on. Without Guarded Releases, the workflow still runs experiments and reports results. You manage the rollout manually instead. If your plan does not include Guarded Releases, update the agent skill definition below to remove the Guarded Release actions.

Setup requires three steps. First, add the LaunchDarkly remote MCP server to your AWS DevOps Agent space. Second, deploy the Experiment MCP Server container to an AgentCore runtime, storing API keys and tokens in AWS Secrets Manager. Third, create your custom agent with the orchestration skill. Use the experimentation skill in AWS DevOps Agent to guide you through defining goals, connecting the MCP servers, and writing the orchestration instructions. The full orchestration skill is included below.

---
name: "experiment-orchestration"
description: "Orchestrates automated experimentation lifecycle using LaunchDarkly Guarded Rollouts, an AI coding agent for implementation, and GitHub Actions for deployment."
---
 
# Automated Experimentation
 
Use this skill when you have a goal you want to move through experimentation (e.g., "increase checkout conversion by 15%", "decrease page load time by 20%").
 
**Core principle: experiment first, then guarded rollout.** Always prove a change on a small, fixed slice of traffic via an A/B experiment before ramping it up through a guarded rollout. Never start a guarded rollout blind — it exists only to scale a change the experiment has already shown to work.
 
**Execution mode:** once the goal is confirmed (Step 1), run Steps 2–8 end-to-end. Async operations (code implementation, release review, deployment, experiment monitoring, rollout monitoring) should be checked periodically, not tight-polled — see the waiting note in each step. Only stop and ask the user something if a step fails unrecoverably (repeated failed release reviews, deployment failure, or an inconclusive/losing experiment result).
 
**The final report (Step 8) is mandatory, not optional.** The moment an experiment or rollout reaches a terminal outcome — winner, loser, inconclusive, or rollback — produce the full report in the same turn you announce the outcome. Don't let a casual "it worked! ????" substitute for the structured report.
 
## Step 1: Goal Clarification
 
Before doing anything, get answers to:
 
1. **What metric measures success?** *(Required)* e.g. conversion rate, page load time, bounce rate. Reserve your error-rate metric as a safety guardrail — never use it as the primary success metric.
2. **What's the target improvement?** *(Required)* e.g. 15% increase, 200ms decrease.
3. **What's the current baseline?** *(Optional — infer from production metrics if not given)*
4. **What parts of the app are in scope?** *(Optional — infer from the codebase if not given)*
5. **Any constraints?** *(Optional)* e.g. no changes to the payment flow.
 
Questions 1–2 are required before proceeding; infer 3–5 where possible and confirm your assumptions with the user before implementing.
 
## Step 2: Hypothesis Generation
 
Explore the target repository/codebase to find a plausible change:
 
1. Search and read the relevant code paths.
2. Think through what UI/UX or logic change could plausibly move the chosen metric.
3. Check whether this hypothesis (or something close to it) has already been tried and failed — look at flag history or archived flags with similar naming. Avoid repeating a known failure.
4. Present the hypothesis to the user before proceeding, along with your reasoning and any inferred assumptions from Step 1.
 
**Before finalizing a flag key, check for collisions:** look up any candidate flag key first.
- Already fully shipped (100% one variation, no split) → already decided, pick a different hypothesis.
- Actively running an experiment → mid-flight, don't compete with it, pick a different hypothesis.
- Doesn't exist → safe to create.
 
## Step 3: Implementation
 
1. Create a boolean feature flag, OFF by default in all environments. Name it with a clear pattern like `exp-<metric>-<short-description>` (e.g. `exp-checkout-conversion-cta-color`), lowercase with hyphens, ~50 chars max.
2. Hand off implementation to your coding agent/tool of choice, with clear instructions to gate the change behind the exact flag key from step 1.
3. This step is asynchronous — check status periodically rather than looping tightly on it.
4. Once implementation completes, move to Step 4 with the resulting branch/PR. If it fails, report the error and stop.
 
## Step 4: Release Readiness
 
Run your standard release/risk review on the PR before merging.
 
- If it passes: merge the PR.
- If it fails: feed the review's specific feedback back into implementation and retry. Cap retries at a small fixed number (e.g. 3 attempts total) — if it still hasn't passed, stop and report the last failure to the user rather than retrying indefinitely.
 
*(If your environment genuinely has no review capability available — e.g., a fully unattended automation context — you can skip straight to merge, but treat that as a deliberate, narrow exception you call out explicitly, not a default. Skipping review removes your only gate against shipping broken code.)*
 
## Step 5: Deployment
 
Deployment typically won't fire automatically on merge if your workflow is manually-triggered (`workflow_dispatch`-only) — you'll need to trigger it explicitly.
 
1. Trigger the deploy workflow on the merge target branch. Treat "already an in-progress deployment for this ref" as expected de-duplication, not an error — don't re-trigger.
2. Poll for status, but let your polling tool's own internal long-poll do the waiting rather than looping tightly yourself.
3. Watch for a "stale" status specifically: if a deployment reports "running" for far longer than normal, cross-check the actual CI run history by commit SHA/timing before assuming it's still in progress — a background poll process may have died without updating the record.
4. **Trigger a deployment at most once per attempt.** If you're unsure whether a previous trigger succeeded, check status first — never re-trigger just because you're unsure.
5. On timeout: stop, check the CI run directly, report the situation, ask how to proceed.
6. On explicit failure: stop and report — do not proceed to the experiment.
7. On success: proceed immediately to Step 6.
 
## Step 6: Experiment Phase (fixed 10%)
 
Prove the change on a small, fixed slice of traffic. Do **not** start a guarded rollout here — that's Step 7, and only after this proves out.
 
1. Turn the flag ON.
2. Configure a fixed 50/50 split across 10% of traffic (a flat allocation, not a staged ramp) on your chosen randomization unit (typically "user"). The remaining 90% of traffic is excluded from the experiment entirely. 
3. Create an experiment with:
   - Exactly one primary metric: the success metric from Step 1.
   - Guardrail metric(s): always include your error-rate metric; add a performance metric (e.g. p95 page load time) too if this is a performance-focused change.
   - Treatments: control (off) at 50%, treatment (on) at 50%, allocated to 10% of total traffic.
4. Start the experiment/data collection.
5. Move to Step 7 to monitor toward a decision.
 
## Step 7: Monitoring & Outcome
 
Check status periodically — don't tight-loop. In an interactive session, check once and report progress, then pick back up later. In an unattended/scheduled context, check once per invocation and persist your progress somewhere durable between runs.
 
**Phase 1 — Prove the experiment at 10% (gate before any rollout):**
 
Watch for statistical significance on the primary metric:
 
- **Significant + positive lift** → experiment proven. Stop the experiment iteration and move to Phase 2.
- **Significant + negative lift** → declare a loser, archive the flag, skip Phase 2, go straight to the Step 8 report.
- **No significance after a reasonable ceiling (e.g. 30 minutes)** → report "inconclusive, need more traffic" and stop; don't proceed to Phase 2.
 
Never declare a winner off a single data point or before your stats engine confirms significance.
 
**Phase 2 — Guarded rollout ramp (only after Phase 1 proves the change):**
 
Start a guarded rollout with:
- The winning ("on") variation as the test, the original as control.
- Same randomization unit as the experiment.
- **Exactly 3 monitored stages, capped well below 100%** — e.g. 20% → 30% → 40%, ~60 minutes monitoring each. Don't add a stage at or above 100%; Guarded-rollout implementations reject stages above 50% audience allocation, and the rollout auto-promotes to 100% itself once the final monitored stage completes cleanly — no explicit 100% stage needed.
- The same primary + guardrail metrics as the experiment, each configured to notify and auto-rollback on regression.
 
Track stage progression. If the rollout rolls back or stops at any point, treat it as a regression: declare failed, clean up the flag (deprecate/archive it), and go to the Step 8 report.
 
Once the final stage completes cleanly and auto-promotes to 100%, declare a winner and go to the Step 8 report.
 
**Retrying after a rollback:** a rollback isn't always caused by your monitored metrics genuinely regressing — it can also be triggered by an unrelated application error surfacing mid-ramp. Before blindly restarting after the user says they've fixed something:
1. Confirm the flag's current state (should be back to 100% control, nothing stuck mid-rollout).
2. Check the change history timing between "advanced to next stage" and "reverted." A rollback within seconds of advancing is inconsistent with a full metric-window regression and points to an external cause instead.
3. If the flag is cleanly reverted and the external cause is confirmed fixed, it's safe to restart the guarded rollout from scratch with the same parameters.
4. Don't silently retry without this check, and don't refuse to retry just because a prior attempt rolled back — a genuinely fixed external cause is a legitimate reason to retry. A metric-driven loser is not — don't retry that.
 
**On any terminal outcome, immediately produce the Step 8 report in the same turn** — a one-line "it worked!" note is fine as a lead-in, but the structured report must follow, not wait for a follow-up request.
 
## Step 8: Report
 
Runs automatically the instant Step 7 reaches a terminal outcome (winner + auto-promoted to 100%; loser; inconclusive; or rollback/failure). Use this exact structure:
 
```
## Experiment Report: [Goal Description]
 
**Date:** [YYYY-MM-DD]
**Goal:** [metric] [direction] by [target]%
**Status:** [achieved / in progress / stalled]
 
### Hypothesis
[What we tried and why]
 
### Implementation
- Flag: [flag_key]
- Files modified: [list]
- Branch: [branch name]
 
### Release Readiness
- [reviewed, passed after N attempt(s) / skipped, per your environment's process]
 
### Experiment Phase (10% fixed split)
- Status: [proven / loser / inconclusive]
- Duration: [time]
- Metric change: [before] → [after] ([+/-]%)
- Statistical significance: [value, confidence interval]
 
### Guarded Rollout Phase (if reached)
- Status: [completed / rolled_back / not started]
- Duration: [time]
- Stages reached: [N of 3 monitored stages]
- If rolled back and retried: [root cause, outcome of retry]
 
### Safety Metrics
- error-rate: [baseline] → [final] ([no regression / regression detected])
- [other guardrails]: [baseline] → [final] ([status])
 
### Next Steps
[What to do next based on the outcome]
```
 
## Safety Rules (the non-negotiables)
 
- Always present the hypothesis before implementing.
- Always run a release/risk review before merging, unless your environment has a deliberate, explicitly-called-out exception.
- **Always prove a change via a fixed small-percentage experiment before starting any guarded rollout** — never ramp blind.
- Always include an error-rate (or equivalent "don't break prod") metric as a guardrail, separate from your success metric.
- Add a performance guardrail (e.g. p95 latency) for performance-focused changes.
- Every rollout metric should be configured to both notify AND auto-rollback on regression — don't rely on notification alone.
- **Cap guarded rollout stages well below 100%** (most platforms reject stages ≥50% audience allocation) and let the platform auto-promote to 100% after the final stage — don't try to add an explicit 100% stage.
- Distinguish a metric-driven rollback (don't retry) from an external-cause rollback (safe to retry once fixed) before restarting a rolled-back rollout.
- The final report is automatic and mandatory on every terminal outcome — never defer it to a follow-up ask.

Conclusion

This post described how AWS DevOps Agent, Kiro CLI, and LaunchDarkly connect into a closed-loop system that turns an improvement goal into a series of measured, safe experiments. The agent runs autonomously on a schedule: it generates hypotheses informed by prior outcomes, creates feature flags before any code change, invokes Kiro CLI in headless mode to implement changes behind those flags, validates through release readiness review, deploys through GitHub Actions and AWS Amplify, and hands off to LaunchDarkly for experiment measurement and guarded rollout. If a guardrail is breached at any point during the rollout, LaunchDarkly reverts flag state at runtime without a redeployment. After each cycle, the agent records what happened and feeds it into the next decision.

This directly addresses the three barriers that slow experimentation:

● Planning cost is reduced because the agent handles hypothesis generation, flag creation, implementation coordination, and validation. The team defines the goal; the system handles the wiring.

● Measurement disconnected from action is addressed because LaunchDarkly monitors metrics in real time and reverts flag state automatically when a guardrail is breached, requiring no redeployment and no waiting for a human to notice.

● Stalled iteration is solved because every outcome is recorded and fed into the next hypothesis automatically. The system does not forget what it learned, and it does not stall between iterations.

The architecture is available to implement today as a reference. The orchestration skill included in this post encodes the full 8-step workflow: goal clarification, hypothesis generation, implementation, release readiness, deployment, experiment, monitoring, guarded rollout, and reporting. Teams define their improvement goal, connect the LaunchDarkly MCP server and the Experiment MCP Server to a DevOps Agent custom agent, and let the system iterate toward the target within the safety boundaries they configure. A more turnkey experience is planned for the future.

Authors

Greg Eppel

Greg Eppel is a Principal Specialist for DevOps Agent and has spent the last several years focused on Cloud Operations and helping AWS customers on their cloud journey.

Jonathan Nolen

Jonathan Nolen is the CPO at LaunchDarkly, the leading platform for Runtime Control for AI software development.

He first joined LaunchDarkly in 2018 and has led the Product, Engineering and Design teams. Currently he is leading the team to build critical infrastructure that helps thousands of customers deliver at agentic speed and still ship software safely. Jonathan was at Atlassian from 2005 until 2018. He helped grow the company from 25 employees to over 2,500 and contributed to multiple Atlassian products. Jonathan and his team also built the Atlassian Marketplace, which in 2024 had done over $3 billion of business for the Atlassian community.

Optimize EKS operations with agents: Reduce MTTR with AWS DevOps Agent and a Kubernetes Operator

Post Syndicated from HoSeong Lee original https://aws.amazon.com/blogs/devops/optimize-eks-operations-with-agents-reduce-mttr-with-aws-devops-agent-and-a-kubernetes-operator/

Introduction

Running workloads on Amazon Elastic Kubernetes Service (Amazon EKS) can involve managing failures like OOMKilled or IP exhaustion. Engineers must repeatedly collect pod logs, trace events, and check node logs—a process that slows at night/weekends, with critical data lost when pods are deleted or nodes become unhealthy. This collection phase is pure overhead on mean time to resolution (MTTR): the incident stays open while an engineer gathers data that a machine could have captured the moment the failure occurred. Automating it shortens MTTR and lets the on-call engineer start at the analysis step instead of the data-gathering step.

Existing AI tools have limitations: K8sGPT only analyzes current resource state, and Amazon Bedrock Agents requires manual tool integration and pipeline setup. Neither provides end-to-end automated incident investigation.

AWS DevOps Agent addresses these gaps—a frontier agent that connects code repositories, observability tools, CI/CD pipelines, and skills to autonomously analyze root causes. This post shows how to build an automated incident response pipeline using the DevOps Agent Operator, a Kubernetes Operator that detects EKS failures and triggers DevOps Agent investigations automatically.

Solution overview

AWS DevOps Agent provides powerful incident analysis. However, it does not detect pod failures inside an EKS cluster on its own. To start an investigation, an external source must trigger DevOps Agent through a webhook. When this trigger occurs, two conditions must be met:

  1. Immediate failure detection: You must detect the failure before the pod is rescheduled or deleted.
  2. Sufficient context: You must send the data that the analysis needs, such as the manifest, logs, events, and node information.

The DevOps Agent Operator is a Kubernetes Operator that meets both conditions automatically.

Why use an Operator?

DevOps Agent runs only when something calls it through a webhook or a manual trigger. In 24/7 operations, doing this manually is not practical. Kubernetes keeps events for only about an hour, restarted containers overwrite their logs, and deleted pods lose them entirely. If you do not collect data right after a failure, the key evidence is gone for good.

DevOps Agent can already run describe and logs with kubectl, and tools like Datadog can detect failures and trigger it.

A separate Operator still adds value for three reasons:

  1. Proactive preservation of volatile data: The Operator detects state changes in milliseconds via watch and preserves data to S3/CloudWatch instantly—before external tool delays (metric collection, alert evaluation, webhook delivery) let evidence disappear.
  2. Selective collection of node-level data: kubectl exposes only container-level and event data, but root causes often live deeper in the node—for example, OOMKilled traces to node dmesg, and IP exhaustion details are in IPAMD introspection. Because the Operator knows the real-time pod-to-node mapping, it collects only what each failure type needs from the exact node.
  3. Encoding operational knowledge in code: The Operator pattern captures human expertise in code, applying different strategies per failure type—dmesg/memory for OOMKilled, previous logs/restart history for CrashLoopBackOff, IPAMD/ENI mappings for IP exhaustion—directly improving analysis accuracy.

In short, the Operator captures evidence at the failure site before it disappears and collects data beyond the reach of kubectl, giving DevOps Agent the best possible material to analyze.

Note: If data collection or an upload to Amazon S3 or CloudWatch Logs fails, the reconcile returns an error and the pod is requeued with exponential backoff rather than dropped, and throttled AWS API requests are retried automatically. The Operator also runs a single reconcile worker and marks each pod with a processed annotation, so a mass failure—for example, 100 replicas crashing at once—is handled one pod at a time and each pod is reported only once. For noisy clusters, WEBHOOK_MIN_SEVERITY and WEBHOOK_SKIP_CATEGORIES let you narrow which failures trigger an investigation.

Architecture

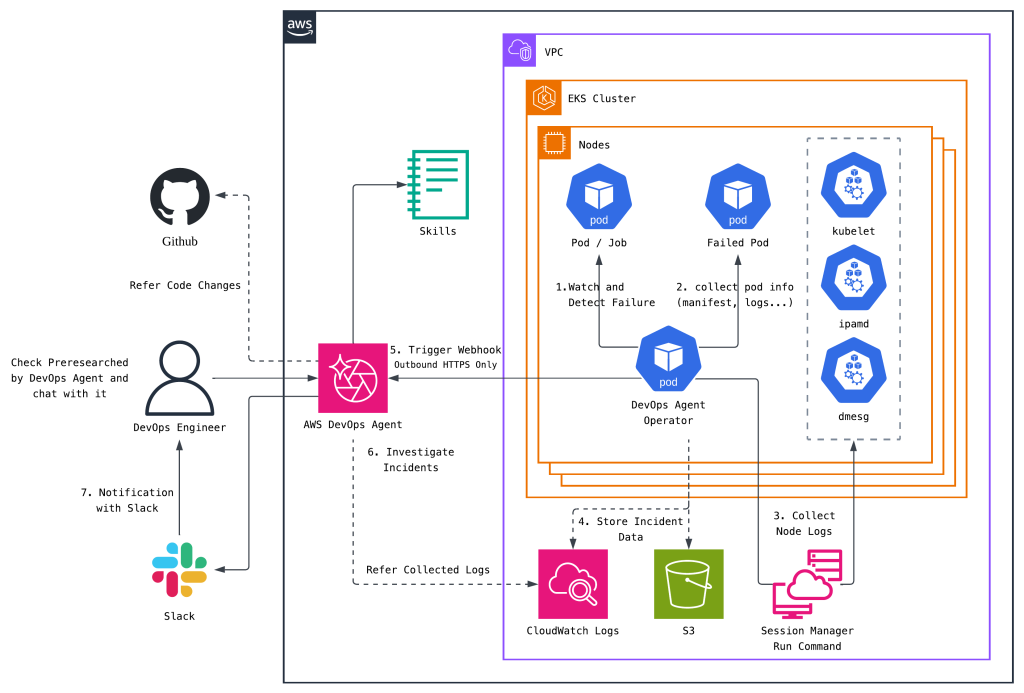
Architecture diagram of the DevOps Agent Operator solution. Inside an Amazon EKS cluster in a VPC, the Operator watches pods and detects failures, collects pod data and node logs, stores the data in CloudWatch Logs and Amazon S3, and triggers AWS DevOps Agent through a webhook. DevOps Agent investigates using skills, the stored logs, and GitHub code changes, then notifies the DevOps engineer in Slack.

Figure 1. End-to-end flow from failure detection to investigation.

The preceding diagram shows the full flow. The DevOps Agent Operator detects a failure inside the EKS cluster and sends the context to AWS DevOps Agent.

Getting started

Prerequisites

  • Region availability: AWS DevOps Agent is available in six AWS Regions—US East (N. Virginia), US West (Oregon), Europe (Frankfurt), Europe (Ireland), Asia Pacific (Sydney), and Asia Pacific (Tokyo). Create your Agent Space in one of these Regions.
  • Node type: Node-level log collection uses AWS Systems Manager Run Command against the EC2 instance that ran the failed pod, so it requires Amazon EKS managed node groups or self-managed EC2 nodes. On AWS Fargate, the Operator still collects Kubernetes-level data—the pod manifest, events, and container logs—but node-level data such as dmesg output and IPAMD introspection is not available.
  • Systems Manager registration: Attach the AmazonSSMManagedInstanceCore policy to your node group’s IAM role so the nodes appear as managed nodes. Without it, node-level collection is skipped and only Kubernetes-level data is collected.

Setting up this solution involves two steps.

The first step is to configure the Agent Space for DevOps Agent. You connect the sources that DevOps Agent needs to analyze an incident, such as code repositories and observability tools. You also set up a generic webhook to receive failure information from the Operator.

The second step is to deploy the DevOps Agent Operator to the EKS cluster. When the Operator detects a pod failure, it collects the context and sends it automatically to the webhook that you set up in the first step.

After you complete these steps, you have an end-to-end pipeline. When a pod failure occurs, DevOps Agent starts an investigation automatically.

Step 1: Configure the Agent Space for DevOps Agent

Configure the webhook

DevOps Agent supports two types of webhooks:

  • Integration-specific webhooks: Created automatically when you set up an integration with an external solution, such as Slack or Datadog.
  • Generic webhooks: Created manually to trigger an investigation from sources that an external integration does not cover.

The DevOps Agent Operator uses a generic webhook. It maintains security through HMAC-SHA256 authentication.

For detailed setup instructions, see the following documentation. This post creates a generic webhook as an example.

Configure the pipeline

You connect GitHub or GitLab so that DevOps Agent can track deployment events and correlate code changes with failures.

  1. Register GitHub or GitLab at the AWS account level.
  2. Connect the repositories that you want to monitor to the Agent Space.

With this connection, DevOps Agent can analyze the recent deployment history and code changes when a failure occurs. DevOps Agent currently supports GitHub and GitLab. For GitLab, you can use both the managed instance and a self-managed instance that is reachable from outside.

For detailed setup instructions, see the following documentation. This post uses GitHub as an example.

Configure communication

DevOps Agent joins your team’s existing communication channels to share its investigation activity. When you connect Slack, you can follow the full process in real time, from failure detection to completed analysis.

For detailed setup instructions, see the following documentation. This post uses Slack as an example.

Step 2: Deploy the DevOps Agent Operator

To install the DevOps Agent Operator, complete the prerequisite steps and the Operator deployment steps in order.

Before you continue, download the source code. You can find the source code at the following link: DevOps Agent Operator source code

1. Prerequisite steps

Before you deploy the Operator to an existing EKS cluster, complete the following prerequisite steps.

1.1. Create an IAM policy for SSM, Amazon S3, and CloudWatch
cat >devops-agent-operator-permission.json <<EOF
{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "SSMCommandExecution",
      "Effect": "Allow",
      "Action": [
        "ssm:SendCommand",
        "ssm:GetCommandInvocation"
      ],
      "Resource": [
        "arn:aws:ec2:<aws-region>:*:instance/*",
        "arn:aws:ssm:<aws-region>:*:*"
      ]
    },
    {
      "Sid": "S3LogStorage",
      "Effect": "Allow",
      "Action": [
        "s3:PutObject"
      ],
      "Resource": "arn:aws:s3:::<s3-bucket-name>/*"
    },
    {
      "Sid": "S3BucketAccess",
      "Effect": "Allow",
      "Action": [
        "s3:ListBucket"
      ],
      "Resource": "arn:aws:s3:::<s3-bucket-name>"
    },
    {
      "Sid": "CloudWatchLogsIncidentStorage",
      "Effect": "Allow",
      "Action": [
        "logs:CreateLogStream",
        "logs:PutLogEvents"
      ],
      "Resource": "arn:aws:logs:<aws-region>:*:log-group:/<cloudwatch-log-group-name>:*"
    }
  ]
}
EOF

Note: To keep this example readable, the policy allows ssm:SendCommand on EC2 instances in the account. In production, restrict it to your cluster’s nodes with an IAM condition key—for example, a StringEquals condition on ssm:resourceTag/eks:cluster-name in a statement that targets only the instance ARN—so that the Operator cannot run commands on unrelated instances. Keep the AWS-RunShellScript document ARN in a separate statement without the condition, because a document carries no instance tags and a single combined statement would deny the call.

Next, create the policy from this file.

aws iam create-policy \
    --policy-name devops-agent-operator-policy \
    --policy-document file://devops-agent-operator-permission.json
1.2. Create a trust policy
cat >devops-agent-operator-trust-policy.json <<EOF
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "AllowEksAuthToAssumeRoleForPodIdentity",
            "Effect": "Allow",
            "Principal": {
                "Service": "pods.eks.amazonaws.com"
            },
            "Action": [
                "sts:AssumeRole",
                "sts:TagSession"
            ]
        }
    ]
}
EOF
1.3. Create an IAM role
aws iam create-role \
    --role-name devops-agent-operator-role \
    --assume-role-policy-document file://devops-agent-operator-trust-policy.json

aws iam attach-role-policy --role-name devops-agent-operator-role --policy-arn=arn:aws:iam::<aws-account-id>:policy/devops-agent-operator-policy
1.4. Associate Pod Identity

EKS Pod Identity associates Kubernetes service accounts directly with IAM roles, enabling pods to access AWS services like Amazon CloudWatch under the principle of least privilege. For more information, see Learn how EKS Pod Identity grants pods access to AWS services.

Pod Identity requires the eks-pod-identity-agent add-on, which is not installed on existing clusters by default. If your cluster does not have it yet, add it first:

aws eks create-addon \
    --cluster-name <eks-cluster-name> \
    --addon-name eks-pod-identity-agent

Then create the association:

aws eks create-pod-identity-association
  --cluster-name <eks-cluster-name>
  --namespace devops-agent-operator-system
  --service-account devops-agent-operator
  --role-arn arn:aws:iam::<aws-account-id>:role/devops-agent-operator-role

2. Build the image

Because the Operator is a reference implementation, the sample provides source code only—no prebuilt container image.
Build the image with the Dockerfile at the following location and push it to a registry that you control, which also keeps the image that runs in your cluster inside your own supply chain. Then use that image to deploy the Operator.
Building the image locally requires Go 1.25 or later. The Operator is built against the Kubernetes 1.35 client libraries and uses only the core Pod, Node, and Event APIs.

For example, suppose that you create a separate repository from all the files under Devops Agent Operator – Sample

You can then build the image through CI/CD with the following GitHub Action as a reference.

name: Build and Push container images to GitHub Container Registry
jobs:
  ...
  build-and-push:
    name: Build and Push Image
    runs-on: ubuntu-latest
    needs: create-tag
    steps:
      - name: Checkout
        uses: actions/checkout@v4
        with:
          fetch-depth: 0
      - name: Setup Go
        uses: actions/setup-go@v5
        with:
          go-version-file: go.mod
      - name: Login to GitHub Container Registry
        uses: docker/login-action@v3
        with:
          registry: ghcr.io
          username: ${{ github.repository_owner }}
          password: ${{ secrets.WRITE_REGISTRY_TOKEN }}
      - name: Set up Docker Buildx
        uses: docker/setup-buildx-action@v3
      - name: Build and Push
        uses: docker/build-push-action@v6
        with:
          context: .
          file: Dockerfile
          push: true
          provenance: false
          no-cache: true
          tags: |
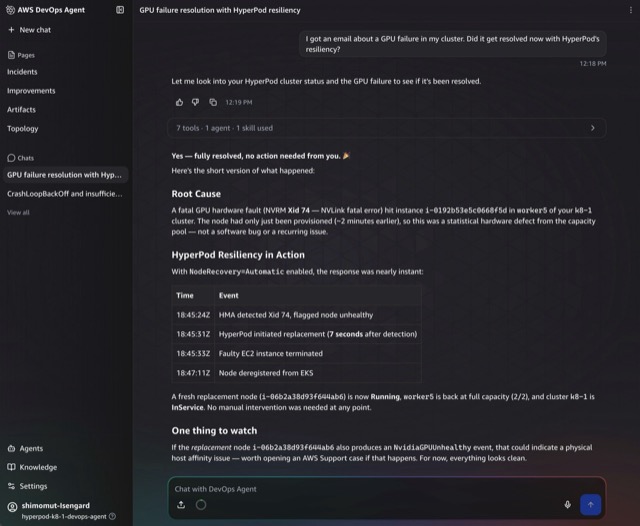
            "ghcr.io/${{ github.repository_owner }}/devops-agent-operator:${{ needs.create-tag.outputs.sha_short }}"
            "ghcr.io/${{ github.repository_owner }}/devops-agent-operator:latest"

3. Deploy the Operator

The following steps are based on the example YAML files for the DevOps Agent Operator. Download the repository, or run the following command to download the files, and then continue.

curl -s https://api.github.com/repos/aws-samples/kr-tech-blog-sample-code/contents/containers/devops-agent-operator/examples?ref=main | jq -r '.[].download_url' | xargs -n1 curl -O
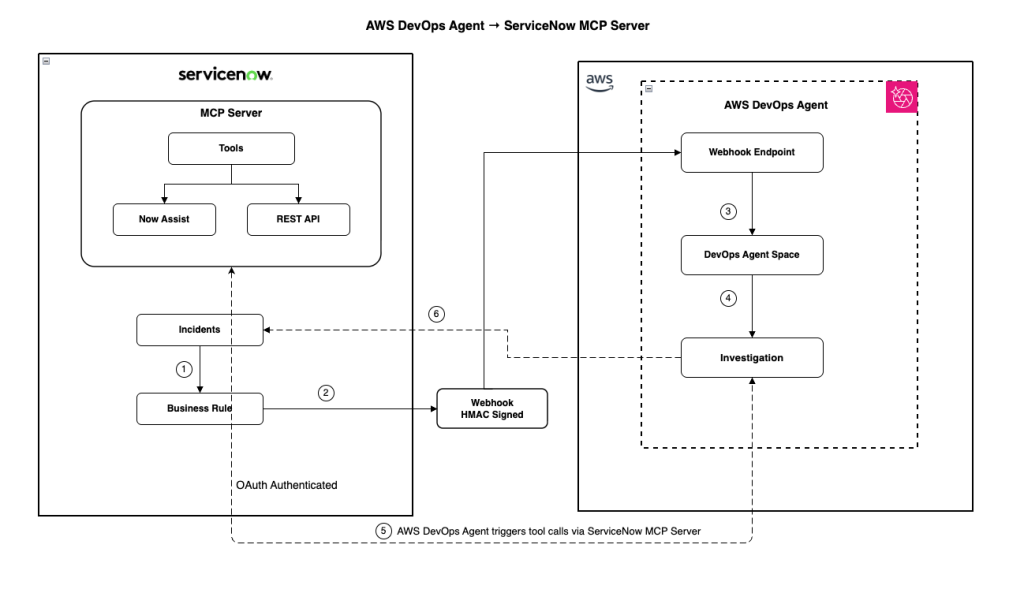
3.1. Set the environment variables

Open the 05-deployment.yaml file, and then change the following variables to values that match your environment.

containers:
- name: manager
    # Use the image that you built in step 2
    image: <operator-image>:latest
    ...
    env:
    # Required settings
    - name: DEVOPS_AGENT_WEBHOOK_URL
        value: "<devops-agent-webhook-url>"
    ...
    - name: EKS_CLUSTER_NAME
        value: "<eks-cluster-name>"
    - name: AWS_REGION
        value: "<aws-region>"
    - name: AWS_ACCOUNT_ID
        value: "<aws-account-id>"
    # Optional settings
    - name: ENABLE_SSM_COLLECTION
        value: "true"
    - name: CLOUDWATCH_LOG_GROUP
        value: "<cloudwatch-log-group-name>"

Also change the 04-configmap.yaml file to values that match your environment.

data:
  # Comma-separated list of namespaces to watch (empty = all namespaces)
  WATCH_NAMESPACES: ""
  # Comma-separated list of namespaces to exclude
  EXCLUDE_NAMESPACES: "kube-system,kube-public,kube-node-lease"
  # Enable AWS SSM node log collection (requires IAM permissions)
  ENABLE_SSM_COLLECTION: "true"
  # AWS region for SSM and S3
  AWS_REGION: "<aws-region>"
  ...

In a shared or multi-tenant cluster, set WATCH_NAMESPACES to the namespaces that your team owns so that the Operator does not collect data from other teams’ workloads. If you leave it empty, the Operator watches every namespace except those listed in EXCLUDE_NAMESPACES.

Note: DevOps Agent references the collected data only while it investigates the incident, so you do not need to retain it long-term. Keeping a short retention period on the CloudWatch log group—and a matching S3 Lifecycle expiration rule on the bucket—keeps the storage cost of this solution minimal.

# Expire the incident logs in CloudWatch Logs after 14 days
aws logs put-retention-policy \
    --log-group-name <cloudwatch-log-group-name> \
    --retention-in-days 14

# Expire the incident objects in Amazon S3 after 14 days
aws s3api put-bucket-lifecycle-configuration \
    --bucket <s3-bucket-name> \
    --lifecycle-configuration '{"Rules":[{"ID":"expire-incident-data","Status":"Enabled","Filter":{"Prefix":"incidents/"},"Expiration":{"Days":14}}]}'
3.2. Create the webhook secret

Edit the 06-webhook-secret.yaml file:

stringData:
  webhook-secret: "<webhook-secret>"
3.3. Deploy the Kubernetes resources
kubectl apply -f .

The example deployment runs a single replica with leader election enabled, so you can raise the replica count for availability without two Operators processing the same failure.

3.4. Verify the deployment
# Check the pod status
kubectl get pods -n devops-agent-operator-system

# Check the logs
kubectl logs -f deployment/devops-agent-operator \
  -n devops-agent-operator-system

When the Operator works correctly, it produces the following logs:

Configuration loaded
Log collector initialized (sinceMinutes: 15)
Webhook client initialized
CloudWatch Logs client initialized
S3 client initialized
Starting workers (worker count: 1)

Use case: Automated analysis of an OOMKilled failure

The following scenario shows how the DevOps Agent Operator and DevOps Agent work together. In this environment, Slack is connected as the notification channel for DevOps Agent, and GitHub is connected as the pipeline.

Scenario

In this scenario, a developer pushed a code change to add a new feature to the web-python service and built a new container image. The developer then updated the running web-python deployment in the EKS cluster with the newly built image.

After the new version rolled out successfully, the developer verified that other services were unaffected. Shortly after, a Slack notification arrived. DevOps Agent reported that the pod that was just deployed had terminated with an OOMKilled status, and that it was investigating the related incident.

kubectl get pods -o custom-columns='NAME:.metadata.name,READY:.status.containerStatuses[*].ready,STATUS:.status.phase,RESTARTS:.status.containerStatuses[*].restartCount,IMAGE:.spec.containers[*].image'
NAME READY STATUS RESTARTS IMAGE
web-python-56b9874b88-tdljd true Running 0 <your-registry>/web-python:sha-96cd2b0

# Deploy the new version
kubectl get pods -o custom-columns='NAME:.metadata.name,READY:.status.containerStatuses[*].ready,STATUS:.status.phase,RESTARTS:.status.containerStatuses[*].restartCount,IMAGE:.spec.containers[*].image'
NAME READY STATUS RESTARTS IMAGE
web-python-645b4f7867-lvqgr true Running 0 <your-registry>/web-python:sha-15d1398

The following steps describe what happens after the pod with the new image is deployed.

Step-by-step flow

1. Failure detection

The kubelet detects the OOM termination of the web-python container and updates the pod status. The informer in the DevOps Agent Operator receives this change in real time. It detects the change from the previous state (Running) to the current failure state (OOMKilled).

kubectl describe po web-python-645b4f7867-lvqgr
Name: web-python-645b4f7867-lvqgr
Namespace: default
...
Annotations: devops-agent.io/failure-type: OOMKilled
                  devops-agent.io/processed: true
                  devops-agent.io/processed-at: 2026-05-30T07:24:43Z

2. Kubernetes-level data collection

As soon as the Operator detects the failure, it collects Kubernetes-level data including pod manifests, pod logs, previous crash logs, and OOM-related event timelines.

3. Node-level data collection

It then gathers node-level data such as kubelet, containerd, and ipamd logs, disk/memory/network usage, and the kernel OOM killer log from dmesg output.

4. Data storage

Based on your configuration, the Operator stores the collected data in CloudWatch Logs and Amazon S3. DevOps Agent can reference the data in CloudWatch Logs during the investigation when it needs to.

5. DevOps Agent trigger

The Operator sends a webhook request that includes an HMAC-SHA256 signature to DevOps Agent. The payload includes investigation instructions for the AI agent.

The DevOps Agent Operator handles steps 1 through 5. You can also see these steps in the logs of the Operator pod.

# 1. Failure detection
2026-05-30T07:24:05Z INFO Failure detected {"controller": "pod", ... "pod": {"name":"web-python-645b4f7867-lvqgr","namespace":"default"}, "failureType": "OOMKilled", "container": "web-python", "exitCode": 137}

# 2-3. Data collection
2026-05-30T07:24:06Z INFO ssm-collector Collecting node logs via SSM {"node": "ip-192-168-1-10.ec2.internal", "instanceID": "i-0123456789abcdef0"}
...

# 4. Data storage
2026-05-30T07:24:08Z INFO cloudwatch CloudWatch Logs upload completed {"logGroup": "cw-log-group-devops-agent-operator", "logStream": "incidents/2026-05-30T07-24-05Z/default/web-python-645b4f7867-lvqgr", "eventsCount": 13}
...

# 5. DevOps Agent trigger
...
2026-05-30T07:24:08Z INFO webhook Webhook request with S3 reference successful {"incidentId": "2026-05-30T07-24-05Z/default/web-python-645b4f7867-lvqgr", "status": 200}

6-7. DevOps Agent Investigation

As DevOps Agent starts the investigation, it shares the incident and its investigation status in the Slack channel that you configured for communication. Through this notification, the engineer can open the Agent Space and follow the investigation in real time.

Slack message from the AWS DevOps Agent app reading "Investigation started: Pod OOMKilled: default/web-python-645b4f7867-lvqgr", with a link to view the investigation.

Figure 2. DevOps Agent announces the OOMKilled incident in Slack.

Skill-based investigation: DevOps Agent automatically selects the skill that matches the incident type. Following the OOMKilled skill, it systematically performs the steps to check the memory configuration, analyze usage patterns, and review the code change history.

The Investigation timeline tab showing the payload sent by the Operator—cluster, pod name, node, failure type OOMKilled, exit code 137, and the Amazon S3 data location—followed by the skill file that DevOps Agent read.

Figure 3. The investigation timeline opens with the payload the Operator sent.

Correlation analysis: In addition to the troubleshooting data that it receives, DevOps Agent connects the following sources for its analysis:

  • GitHub: Checks recent code changes for memory-related modifications.
  • CloudWatch: Checks memory usage trends in Container Insights.

In this scenario, you can see that DevOps Agent starts its analysis from the data that the Operator uploaded to CloudWatch Logs, as the skill specifies.

The timeline showing the OOMKilled symptom and four investigation tasks running in parallel: search-app-logs, search-performance-metrics, search-code-repos, and check-cloudtrail-changes.

Figure 4. DevOps Agent runs four investigation tasks in parallel.

The code repository task listing the files DevOps Agent read from the connected repository, including the Kubernetes deployment manifest, the application source, the Dockerfile, and the requirements file.

Figure 5. DevOps Agent reads the manifest and application code from the connected repository.

The skill also specifies the relationship between the GitHub repository that you connected as a pipeline and the container image. DevOps Agent uses this information to review the code changes that occurred recently.

This information helps DevOps Agent identify the root cause of the incident.

Two findings on the timeline: an unbounded processed_records list leaking about 20 Mi per minute, and a deployment updated to the image that contains the leaking code.

Figure 6. Two findings: the unbounded list and the deployment that introduced it.

8. Analysis results

DevOps Agent organizes the analysis results:

  • Investigation Timeline: This tab shows the agent’s investigation steps—which skills it referenced and what data it analyzed.
    This view helps you optimize the skill to guide investigations more efficiently.
  • Root causes: This section summarizes the root cause from the overall investigation.
Unbounded `processed_records` list in web-python application causes memory leak at ~20Mi/min
The Python Flask application in image `<your-registry>/web-python:sha-15d1398` contains a background worker thread (`_cache_worker`) that generates 500 records every 2 seconds and appends processed results to an in-memory list called `processed_records`. Unlike the `cache` list which has eviction logic capped at 80MB (`CACHE_SIZE_MB`), the `processed_records` list has NO eviction or size limit — it grows unboundedly. With Python/Flask overhead (~30MB) + the cache growing toward its 80MB cap, the remaining headroom within the 200Mi container memory limit is exhausted in approximately 10 minutes. This was confirmed by two consecutive pod instances (lvqgr and 7rwdj) both being OOMKilled after exactly ~10 minutes of runtime.

With the investigation from DevOps Agent, the engineer can identify the cause of the problem.

In the preceding example, you can see how the agent identifies a critical memory leak in the recently changed service code. It then reasons about the cause of the OOM event together with the commit ID.

The Root cause tab showing the memory leak summary with two supporting observations: the pod being OOMKilled twice within 30 minutes under a 200Mi limit, and the audit log entry for the image change.

Figure 7. The Root cause tab with its supporting observations.

9. Analysis and mitigation plan through chat

The engineer reviews the results and, when needed, can ask DevOps Agent follow-up questions:

  • “Check whether other services show a similar memory growth pattern.”
  • “Will fixing it with approach A help solve the problem?”

In the following example, the engineer asks whether increasing the pod memory limit will help solve the problem. The agent responds based on its investigation.

A chat panel where the engineer asks whether raising the pod memory limit to 250Mi would mitigate the issue, and DevOps Agent answers that it would only add about 2.5 minutes before the same OOMKill.

Figure 8. Follow-up chat on whether a higher memory limit would help.

As this shows, DevOps Agent goes beyond simple problem analysis. It uses the context that it accumulated during the investigation to respond to the engineer’s follow-up questions with detailed explanations.

In this scenario, the problem is a logic issue in the source code. For that reason, DevOps Agent could not provide a clear plan at the Kubernetes or AWS infrastructure level. However, based on the root cause, you can receive a mitigation plan related to a rollback.

The Mitigation plan tab proposing a rollback of the web-python deployment to the previous image, with numbered preparation steps and the AWS CLI commands to verify the cluster first.

Figure 9. The Mitigation plan tab proposes a rollback.

Conclusion

In this post, we introduced the DevOps Agent Operator – a Kubernetes Operator that automatically detects EKS workload failures, collects diagnostic data, and triggers AWS DevOps Agent for root cause analysis.

By combining these two tools, engineers gain the following benefits:

  • Faster response: Automatic data collection and analysis as soon as a failure occurs, even during nights and weekends.
  • No loss of information: Immediate preservation of all troubleshooting data before a pod is rescheduled or deleted.
  • Comprehensive analysis: DevOps Agent analyzes code repositories, observability tools, and CI/CD pipelines together to trace root causes that are hard to find with a single tool.
  • Organizational knowledge: Through skills, the solution reflects your team’s operational knowledge, enabling incident response with consistent quality.
  • Continuous improvement: Proactive recommendations based on accumulated incident data help prevent future incidents.

Looking ahead, there are several ways to extend this solution:

  • Support for more resource types: Extend monitoring beyond pods to Job, CronJob, Deployment, and StatefulSet.
  • MCP server integration: DevOps Agent supports Model Context Protocol (MCP) servers, enabling advanced workflows such as querying additional resources during analysis or performing pattern analysis on past incidents.
  • Proactive pattern analysis: As incident data accumulates in Amazon S3 and CloudWatch Logs, DevOps Agent can identify recurring patterns – such as “OOMKilled repeats every Monday morning” – and recommend preventive measures.

The DevOps Agent Operator project is open source on GitHub. It is a reference implementation rather than a supported product: use it as a working example of how to encode your own detection conditions and collection strategy for the failures your team actually sees.

To try it yourself, clone the repository, follow the deployment steps in this post, and point the Operator at your own Agent Space webhook. Start with a non-production cluster and a narrow WATCH_NAMESPACES list, then widen the scope once you see the investigations that DevOps Agent produces.

References

HoSeong Lee

HoSeong Lee

HoSeong is a Cloud Support Engineer at AWS, specializing in containers, infrastructure as code, and CI/CD. With a background in web development and DevOps, he helps customers troubleshoot issues and keep their AWS workloads running reliably. He has deep expertise in Amazon EKS and is interested in applying agentic AI to automate day-to-day operations.

Boyoung Kim

Boyoung Kim

Boyoung is a Cloud Support Engineer at AWS, focusing on containers, infrastructure as code, and CI/CD. She analyzes recurring customer issues and turns proven support patterns into reusable guidance, helping customers build more stable and efficient production workloads.

YoungJoon Jeong

YoungJoon Jeong

YoungJoon is a Specialist Solutions Architect at AWS, specializing in Kubernetes platform engineering and AI/ML infrastructure. He works with enterprises across APJC to design and build production Amazon EKS environments spanning agentic AI platforms, GPU scheduling, hybrid infrastructure, and security governance. He also maintains an open source engineering playbook covering EKS best practices, AI platform architecture, performance benchmarks, and cloud-native operations.

AI-driven software delivery with Kiro, AWS DevOps Agent and Bluebox by Dynatrace

Post Syndicated from Philipp Ushiromiya original https://aws.amazon.com/blogs/devops/ai-driven-software-delivery-with-kiro-aws-devops-agent-and-bluebox-by-dynatrace/

This post was co-written with Michael Stephan, Senior Principal Product Manager, and Christian Kreuzberger, Principal Software Engineer, at Dynatrace.

AI-driven software delivery changes how code gets written, but not what production demands of it. A generated change still has to fit the traffic your service receives, the dependencies it calls, and the capacity limits it runs within. Without that context, you validate the change after it ships, which adds rework and deployment risk.

Kiro turns intent into specifications, code, and pull requests. AWS DevOps Agent investigates incidents and proposes mitigations. Bluebox by Dynatrace supplies the runtime topology, dependency, and traffic data that both draw on, so each change and each investigation is grounded in how the system behaves rather than how it’s expected to behave. In this post, we will follow a travel-booking example from feature design through post-deployment remediation. You’ll see how telemetry from Bluebox shapes a change in Kiro, how AWS DevOps Agent investigates an incident, and where human review and existing CI/CD controls remain in the process.

What are Kiro and AWS DevOps Agent?

Kiro is an agentic development environment that applies AI across the software development lifecycle. Its spec-driven workflow organizes a feature request into requirements, design, and implementation tasks before generating any code.

AWS DevOps Agent is a frontier agent for software delivery and operations across AWS, multicloud, and on-premises environments. It investigates incidents, identifies likely root causes, and recommends mitigations. Its release management capability (Preview) reviews code for release readiness and runs release tests before deployment.

Bluebox by Dynatrace: Helps agents ship the code you trust to production

To close the loop between code generation and production context, Kiro and AWS DevOps Agent rely on real-time production intelligence. This is where Bluebox by Dynatrace fits in. Bluebox provides the observability foundation that detects problems, measures their impact, and surfaces the runtime application topology, service dependencies, and actual traffic patterns that make AI-generated code and autonomous investigations truly production-aware.

Without production telemetry, AI-generated code operates in a vacuum – it cannot know that an endpoint handles 40:1 read-to-write ratios, that a service dependency has specific latency characteristics, or how API traffic fluctuates throughout the day. Bluebox grounds actions taken by Kiro and AWS DevOps Agent in how the system actually behaves, not in assumptions about how it should behave.

How the closed loop works

The combination of Kiro, AWS DevOps Agent, and Bluebox creates a continuous cycle from development through production and back:

  • Production-aware code generation: Before code is written, Kiro retrieves runtime context from Bluebox – service topology, traffic patterns, and resource utilization. Kiro’s spec-driven workflow translates this context into requirements and generates code that aligns with real production conditions from the first commit.
  • Confident code review: Kiro generates pull requests with production evidence attached. The release management capability in AWS DevOps Agent reviews the change for dependency impacts, drifts from internal standards, and production readiness – running autonomous tests in isolated environments.
  • Continuous monitoring: After deployment, Dynatrace continuously monitors application behavior. When an anomaly occurs, Bluebox detects it and surfaces full production context.
  • Autonomous investigation: Bluebox triggers AWS DevOps Agent with the relevant observability and topology data. AWS DevOps Agent performs a deep investigation, correlating telemetry, logs, infrastructure changes, and deployment history to pinpoint the root cause.
  • Automated remediation: AWS DevOps Agent generates the mitigation plan from the observability and runtime data that Bluebox provides. Bluebox adds that plan to the investigation report and files it as a GitHub issue. Kiro then proposes a production-aware fix as a pull request for your review, completing the loop.

Figure 1: Bluebox supports the closed loop from feature build to operations.

Next, we walk through a concrete example of this workflow in action.

Walkthrough

We follow a travel-booking application through two connected scenarios: shipping a new feature with production context, then responding to a production incident after it deploys.

Building a production-aware feature

Consider a team enhancing a travel booking application to improve customer experience. You begin by describing a new feature in Kiro, such as updating how products are displayed or adjusting backend logic to support new capabilities. In this case, we are using Kiro IDE.

Figure 2. A feature request in Kiro, with the project’s steering documents loaded for context.

Kiro’s spec-driven workflow expands this request into structured requirements before writing code. You connect Kiro to the Bluebox CLI to retrieve the full production context from Dynatrace: service dependencies, runtime topology, and observed traffic. The following figure shows how Kiro queries current load data for the flight-search path, including the ratio of Amazon DynamoDB reads to writes. Kiro composes and runs the CLI command on your behalf, so you don’t have to type it or set environment variables by hand. The command and its output stay visible in the session, so you can approve it before it runs and check what was retrieved before acting on it. In this case, the command queries the Bluebox API for the requested metrics. The output returns read and write counts per second for the DynamoDB table behind flight search, along with the services calling it.

Figure 3. Kiro runs the Bluebox CLI, then reads the codebase with production context before proposing changes.

The telemetry shows the flight-search endpoint is read-heavy. Users repeatedly query the same routes, at roughly 40 reads for every write against the DynamoDB table. Repeated identical reads are what a cache absorbs, so Kiro proposes an Amazon ElastiCache layer in front of the table, sized to the active working set derived from the observed request distribution. Without the read-to-write ratio, the same request could have produced a larger provisioned table or an added read replica, neither of which addresses repeated identical queries.

Kiro generates the code that implements the change and opens a pull request in GitHub for review. Nothing reaches production until a reviewer approves and merges it. The pull request carries the code changes and the Bluebox telemetry that justified them, so reviewers assess the decision against the same telemetry Kiro retrieved.

Figure 4. Kiro pushes a feature branch and opens a pull request in GitHub.

After review and approval through standard processes, a reviewer merges the pull request, and the existing CI/CD pipeline deploys the change.

Figure 5. The pull request is reviewed and merged through the standard GitHub workflow.

Responding to a production incident

With the feature live, Dynatrace continues monitoring the application. A marketing promotion then drives traffic above the observed baseline, and failed requests start to appear. The loop now runs from operations back to development.

Figure 6. Dynatrace detects a spike in failed requests, surfacing the production incident.

Bluebox collects the relevant observability and topology data, runs an initial root-cause analysis, then opens an autonomous investigation in AWS DevOps Agent. The AWS DevOps Agent multi-agent reasoning architecture decomposes the investigation across specialized capabilities that each examine one class of evidence: telemetry, logs, infrastructure configuration, and recent deployment activity.

Figure 7. Bluebox delegates an autonomous investigation to AWS DevOps Agent.

AWS DevOps Agent locates the cause in the DynamoDB table rather than the new cache. The table’s billing mode had been changed to PROVISIONED, with 5 read capacity units (RCU) and 5 write capacity units (WCU) and no auto scaling. The ElastiCache layer absorbs repeated reads, but cache misses and all writes still reach DynamoDB, and at promotion traffic that residual load exceeds 5 RCU and 5 WCU. AWS DevOps Agent produces a mitigation plan with specific remediation steps. This plan and the full investigation context from Bluebox, is documented as a GitHub issue.

Figure 8. GitHub issue is created with results from Bluebox and AWS DevOps Agent.

Kiro proposes a production-aware fix as a new pull request – including the root-cause analysis, supporting telemetry, and recommended configuration changes.

Figure 9. The Kiro coding session works on the GitHub issue and creates a remediation Pull Request.

The fix is reviewed, merged, and deployed like any other change. Dynatrace then confirms that error rates and response times return to baseline, which closes the loop.

Conclusion

In this post, we showed how Kiro, AWS DevOps Agent, and Bluebox by Dynatrace connect production telemetry with feature development and incident remediation. The travel-booking example keeps human review and existing CI/CD controls in the process while passing operational context from production back to development.

To get started pick one application and define a measurable outcome, such as investigation time, change-failure rate, or pull-request review time. Then:

  1. Download Kiro and start building with spec-driven development
  2. Enable AWS DevOps Agent for autonomous incident investigation and remediation
  3. Get started with Bluebox by Dynatrace to complete the loop with production intelligence

Simone Pomata

Simone is a Principal Solutions Architect at AWS. He has worked enthusiastically in the tech industry for more than 10 years. At AWS, he helps customers succeed in building new technologies every day.

Philipp Ushiromiya

Philipp Ushiromiya is a Solutions Architect at AWS. He helps customers drive organizational modernization through cloud-native solutions and DevOps practices. His passion for GenAI enables teams to accelerate development with cutting-edge technology.

Michael Stephan

Michael Stephan is a Senior Principal Product Manager at Dynatrace with over 15 years of experience in the IT industry. He specializes in helping Dynatrace customers effectively monitor and optimize their cloud environments.

Christian Kreuzberger

Christian Kreuzberger is a Principal Software Engineer at Dynatrace, with over 20 years of experience in the IT industry. At Dynatrace, he builds software that helps cloud-native and AI-native organizations automate their operations.

From clickops to governed IaC: CloudFormation drift detection in practice

Post Syndicated from Leen Alattas original https://aws.amazon.com/blogs/devops/from-clickops-to-governed-iac-cloudformation-drift-detection-in-practice/

AWS environments that have grown organically over time often share a common characteristic: infrastructure provisioned through the AWS Management Console, SDKs, or CLI without corresponding Infrastructure as Code (IaC) templates. This practice is commonly referred to as “ClickOps,” a term describing any infrastructure change made outside of a codified, version-controlled workflow. Whether changes happen through the console, the AWS CLI, or application SDKs, the result is the same: resources exist without a declarative template to describe their intended state. 

Over time, these manual changes accumulate, creating environments where Amazon Virtual Private Cloud (Amazon VPC) configurations, Amazon Elastic Compute Cloud (Amazon EC2) instances, and Amazon Simple Storage Service (Amazon S3) buckets exist without a single AWS CloudFormation template to describe them. 

Organizations that find themselves in this position have a clear opportunity. CloudFormation’s IaC Generator provides a practical starting point for bringing existing infrastructure under declarative management. It scans an AWS account and produces CloudFormation templates from existing resources, solving the first and most fundamental challenge: you cannot govern infrastructure you cannot see. 

However, generating a template is only the beginning. What follows is the operational thinking behind turning a generated template into something a team can govern and automate: the decisions, trade-offs, and organizational habits that determine whether IaC adoption succeeds long-term. 

IaC Generator: making the invisible visible 

CloudFormation’s IaC Generator scans an AWS account and produces CloudFormation templates from existing resources: Amazon VPCs, subnets, Amazon EC2 instances, Amazon S3 buckets, AWS Identity and Access Management (IAM) roles, and more. It solves the foundational problem of any ClickOps-to-IaC migration: establishing visibility into what exists and how it is configured. 

How it works at a high level 

Scan — IaC Generator discovers resources in the account by querying AWS Cloud Control API, identifying what exists regardless of how it was provisioned. 

Generate — It produces CloudFormation templates that represent the current state of those resources, mapping properties, dependencies, and relationships. 

Review — Teams evaluate the generated templates, reconcile any gaps, and decide how to bring each resource under management. 

This process eliminates weeks of manual documentation work. Instead of engineers mapping infrastructure by hand, IaC Generator produces a baseline in minutes. For a team managing 200+ resources across multiple VPCs, this can compress a multi-sprint effort into a single planning session. 

Understanding what the generator produces 

The generated templates capture the current state of resources, including every manual configuration and accumulated change. Before acting on a generated template, teams should understand what it represents and what it does not. 

Important: IaC Generator does not cover all resource types supported by CloudFormation. Before committing to an import path for any resource, verify that the resource type is supported. Coverage continues to expand, but teams should confirm support for their specific resource types before planning their migration approach. 

The generated template provides an inventory of infrastructure and surfaces implicit dependencies that were never documented. However, a template in a repository does not prevent out-of-band changes, enforce review processes, or protect against drift. Visibility is the prerequisite for control, not a substitute for it. 

Import or recreate: making the right decision for each resource 

When bringing existing resources under CloudFormation management, teams must decide on a per-resource basis whether to import a resource into a stack or to recreate it cleanly. The right choice depends on the specific characteristics of each resource: its criticality, how much operational disruption is acceptable, the complexity of its dependencies, and the technical limitations of the tooling. CloudFormation does not support partial adoption of an existing resource: a resource is either fully imported into a stack or newly provisioned through a stack. This is what makes the decision binary and per-resource rather than incremental. 

A note on configuration drift in this context: configuration drift occurs when the actual state of a resource diverges from what is defined in a template. A resource that was provisioned manually may be in a perfectly valid operational state, but it has no template against which to measure compliance. The goal of importing is to establish that baseline, not to imply the current configuration is inherently flawed.

Factor  Import existing resource  Recreate with new stack 
Resource criticality  High: production, live data, tight dependencies  Lower: dev/test, stateless, easily replaceable 
Manual changes  Significant: many out-of-band modifications  Minimal: resource is close to desired state 
Downtime tolerance  Zero: any interruption is unacceptable  Acceptable: brief maintenance window tolerable 
Template fidelity  Lower: generated template may be imperfect  Higher: full control over the final template 
Dependency complexity  High: cross-service dependencies difficult to isolate  Lower: resource can be isolated and rebuilt cleanly 

Technical limitations to consider 

Beyond operational factors, the IaC Generator has technical constraints that should inform the import-versus-recreate decision: 

  • Resource type coverage: Not all resource types supported by CloudFormation are supported by IaC Generator. Before committing to an import path, verify that the specific resource types are supported. If a critical resource type is not covered, the template must be written manually. 
  • Write-only properties: Some resource properties (such as passwords or secrets) are write-only and cannot be read back during scanning. Generated templates show placeholder values for these, requiring manual reconciliation. In production environments, this may require integration with AWS Secrets Manager or a similar secrets management solution. 
  • Hard-coded values: Generated templates produce literal values rather than parameterized inputs. Plan for a refactoring pass to introduce parameters, mappings, and conditions. 
  • Cross-account and cross-region references: IaC Generator operates within a single account and region. Resources with dependencies spanning accounts or regions require additional manual template work. 

For production resources, stateful workloads, and resources with complex dependency graphs, import is generally the appropriate default. The import operation brings resources under CloudFormation management without recreating them, preserving their current state. The trade-off is that the generated template becomes the starting point, and teams must reconcile any gaps between that template and actual resource state before making subsequent changes. 

Recreation is more appropriate when a resource can tolerate a brief maintenance window, when accumulated manual changes make a clean start more efficient than reconciliation, or when the architecture is being redesigned as part of the migration. 

The most effective approach is to segment the inventory by resource type, criticality, and configuration complexity, then match the strategy to each segment. An Amazon VPC that has been modified extensively over three years presents a different challenge than an Amazon S3 bucket created last month. 

Organizing stacks for operational reality 

A common challenge after bringing resources under CloudFormation management is determining the appropriate stack boundaries. Placing all resources into a single monolithic stack creates operational risk: changes to VPC and subnet infrastructure can inadvertently affect application resources, a rollback on an application deployment can revert infrastructure changes, and accountability becomes diffuse. When ownership is unclear, incident response slows. 

Organizing stacks around lifecycle, ownership, and change frequency addresses this challenge. The key principle is to group resources that share the same rate of change and the same responsible team: 

When these criteria conflict, ownership takes precedence: a shared resource should reside in the stack owned by its primary responsible team, with cross-stack references providing access to consuming teams. 

  • VPC and subnet infrastructure changes infrequently and is typically managed by a platform or infrastructure team. 
  • Application infrastructure changes frequently and is managed by the application teams that deploy to it. 
  • Security controls warrant their own stacks under security team ownership, insulated from application deployment cycles. 

Cross-stack references, through CloudFormation exports and imports, preserve these boundaries while maintaining relationships between stacks. A VPC stack exports Amazon VPC and subnet IDs; application stacks import them. This separation means that application deployments do not modify network configuration, and VPC or subnet changes do not require redeploying application stacks. 

Note: this separation does not eliminate all cross-cutting concerns. Changes to security groups or network ACLs, for example, may still require coordination with application teams. The goal is to reduce unintended coupling, not to eliminate all interdependency. 

This structure makes governance at scale tractable. When stacks have clear boundaries and named owners, drift detection becomes actionable. Teams know exactly who owns a drifted resource and who needs to respond. 

Drift detection: moving from reactive to continuous 

Defining drift: Configuration drift occurs when the actual state of a resource diverges from what is declared in its CloudFormation template. Drift can originate from manual console changes, AWS CLI or SDK operations, automated processes that modify resources outside of CloudFormation, or any action that bypasses the IaC workflow. Drift is not inherently a failure; it often reflects legitimate operational decisions made under time pressure. The challenge is maintaining awareness of these changes so they can be evaluated and reconciled deliberately. 

CloudFormation’s native drift detection tells teams whether resources match their templates. What it cannot do on its own is provide continuous monitoring. Manual, on-demand checks are valuable, but they are reactive. By the time a team runs one, the drift may have already caused a downstream issue. 

Automating drift detection with Amazon EventBridge 

Continuous drift detection requires three capabilities: scheduled detection runs, event capture when drift is found, and routing of alerts to the appropriate team. Amazon EventBridge provides the orchestration layer that connects these capabilities: 

  • Schedule drift detection: Configure an EventBridge rule with a cron expression to trigger the DetectStackDrift API on critical stacks at regular intervals (for example, every 6 hours for production stacks, daily for non-production). This is a custom configuration, not a built-in default; teams define the schedule based on their operational requirements. 
  • Capture drift events: CloudFormation emits events to the default EventBridge event bus when drift detection completes. Create rules that filter for CloudFormation Stack Drift Detection Status Change events where the drift status is DRIFTED. 
  • Automated remediation (with caution): For well-understood, low-risk drift patterns in non-production environments, EventBridge can trigger an AWS Lambda function that applies a drift-aware change set. However, automated remediation in production environments requires careful consideration. See the guidance below on remediation policy. 

Remediation policy: a deliberate decision 

Whether drift triggers a notification or an automated correction should be a deliberate, documented policy decision. Several factors argue for caution with automated rollbacks: 

  • Drift is typically detected well after it occurred. The change was not random; a person or process determined it was necessary at the time. 
  • Automatically reverting a change without understanding why it was made can reintroduce the problem it was intended to solve. 
  • In production environments, the safest default is to alert the owning team and let them evaluate whether the drift should be reconciled into the template or reverted. 

Automated remediation is most appropriate in controlled environments (development, staging) or for narrowly-scoped, well-understood drift patterns where the risk of unintended consequences is minimal. 

Drift-aware change sets 

Drift-aware change sets extend drift awareness into the deployment pipeline. Before applying changes, a drift-aware change set evaluates the actual current state of a stack rather than the last known state. This is critical when someone made a manual change under operational pressure but has not yet reconciled it. A routine deployment should not silently overwrite a deliberate operational decision. 

This capability supports the position that drift should generally be reconciled deliberately rather than reverted automatically. When a drift-aware change set reveals unexpected state, the deploying team can pause, investigate, and decide whether to incorporate the drift into the template or proceed with the planned change. 

Over time, drift data provides organizational insight beyond individual resource compliance. The same resource drifting repeatedly, or the same team consistently making out-of-band changes, points to gaps in process, tooling, or team capacity. That signal is valuable only if someone is reviewing it systematically. 

The operational maturity journey 

Moving from ClickOps to fully governed CloudFormation management is not a single migration event. The progression moves through four recognizable stages: 


Level  Stage  What it means 
Level 1  Visibility  The team knows what exists. IaC Generator provides templates that represent the infrastructure. Necessary, but not sufficient. 
Level 2  Control  Resources are under CloudFormation management. Changes route through templates and change sets. Drift is detectable. 
Level 3  Automation  Drift detection runs on schedule. CI/CD pipelines incorporate drift awareness. Governance is a property of the deployment process. 
Level 4  Governance  Compliance policies are enforced automatically. Drift outside defined parameters triggers remediation or escalation. Infrastructure state is continuously validated against policy. 

Moving from visibility to control is primarily an organizational challenge. It requires three deliberate shifts: 

  1. Ownership

Every CloudFormation stack needs a named team responsible for its drift state. Establish this accountability through: 

  • A mandatory team-owner tag applied to every stack. 
  • Integration with AWS Service Catalog to enforce ownership metadata from provisioning onward. 
  1. Process

Changes need to be routed through CloudFormation, not around it. Any change made outside of the IaC workflow (whether through the console, CLI, or SDK) is a potential source of drift. Governance controls include: 

  • AWS CloudTrail with EventBridge rules that flag API calls made outside of CloudFormation. 
  • A defined reconciliation window (for example, 24 hours for production hotfixes) that acknowledges operational reality while maintaining accountability. 
  1. Feedback loops

Point-in-time drift snapshots are useful, but trends over time are more valuable for identifying systemic issues. Build feedback mechanisms that surface patterns: 

  • Use Amazon Athena to query historical drift data for recurring patterns. 
  • Feed drift metrics into existing operational review cadences. 

Conclusion 

IaC Generator makes the invisible visible. It turns infrastructure provisioned outside of IaC workflows into CloudFormation templates that can be versioned, reviewed, and automated. The template is not the destination; it is the starting point for building infrastructure that teams can change with confidence and govern at scale. 

The real work is organizational: assigning stack ownership, routing changes through CloudFormation, building continuous drift awareness, and treating drift data as a signal about process gaps rather than as a compliance checkbox. Organizations that approach this as a cultural shift alongside a technical migration are the ones that sustain the gains long-term. 

Getting started 

For teams ready to implement this approach, the following resources provide step-by-step guidance: 

  • Implement drift notification routing: Use AWS Chatbot with EventBridge to route alerts to team channels, or trigger ticket creation via AWS Lambda. 

Leen AlAttas is a Technical Account Manager in the AWS Enterprise Support organization based in Riyadh, Saudi Arabia, where she has spent the past year helping enterprise customers optimize their cloud operations. She specializes in security and works closely with organizations to strengthen their AWS security posture. 

John Chebib is a Senior Technical Account Manager at AWS based out of Bahrain. He works with customers providing technical assistance and architectural guidance on various AWS services. He brings several years of experience in data analytics and architectural roles for various large-scale enterprises.

Streamline your GitHub journey with AWS CodePipeline and AWS DevOps Agent

Post Syndicated from Anjani Reddy original https://aws.amazon.com/blogs/devops/streamline-your-github-journey-with-aws-codepipeline-and-aws-devops-agent/

Introduction

When CI/CD deployment failures occur for GitHub hosted applications,  AWS DevOps Agent reduces the hours that Development and Site Reliability Engineering (SRE) teams typically spend manually investigating across multiple AWS services, logs, and pipeline stages. This process delays critical deployments and impacts software delivery velocity. This is especially true when teams need to correlate data between GitHub commit histories, AWS CodePipeline execution logs, and Amazon CloudWatch metrics. When continuous integration and continuous delivery (CI/CD) pipelines fail, engineers often find themselves context-switching between GitHub pull requests, code build logs, deployment artifacts, and downstream service health metrics. This process of identifying root causes can extend resolution time from minutes to hours, especially in multi-service architectures.

AWS DevOps Agent reduces this manual investigation by automatically correlating pipeline failures with specific code changes. Rather than spending hours manually tracing deployment failures through multiple systems, engineers can use AWS DevOps Agent to perform this correlation. It identifies which specific code changes caused pipeline failures and provides remediation guidance. The agent analyzes pipeline failures, correlates them with specific commits and pull requests, and identifies root causes across the deployment chain.

AWS CodePipeline combined with AWS DevOps Agent helps address this challenge by creating a streamlined path from GitHub repositories to AWS deployments. This solution reduces manual handoffs, reduces configuration complexity, and provides end-to-end visibility across the entire development lifecycle.

In this post, you learn how to integrate AWS DevOps Agent with your GitHub repositories to automatically correlate deployment failures with specific commits, providing root cause analysis and remediation steps across your entire CI/CD pipeline.

Solution overview 

Modern software delivery teams face a persistent challenge: when deployments fail, engineers spend valuable time manually correlating logs, tracing pipeline errors, and diagnosing root causes across disconnected tools. This reactive cycle slows recovery and increases mean time to resolution (MTTR). By integrating the AWS DevOps Agent with GitHub, AWS CodePipeline, Amazon CloudWatch, and AWS Lambda, teams can shift from manual triage to automated incident investigation, directly within their existing GitHub-based workflows.

This solution integrates AWS DevOps Agent with GitHub to automate deployment failure investigation. The following sections explain the architecture and operational benefits.

How it works​ 

The architecture creates an automated monitoring and remediation flow that monitors your deployment pipeline and responds to issues. Your source code resides in a GitHub repository, and AWS CodePipeline orchestrates the build, test, and deployment stages. Amazon CloudWatch continuously monitors pipeline execution metrics and logs and generates alarms when it detects anomalies or failures, such as failed build stages, deployment rollbacks, or threshold breaches in downstream application of health metrics. When a failure occurs, it generates an error metric in CloudWatch. The CloudWatch Alarm detects this error and transitions to an ALARM state, which directly invokes the WebHook Executor Lambda. The WebHook Executor then sends an authenticated HTTP POST request to DevOps Agent, which receives the incident and begins an investigation.

Webhook integration acts as the bridge between the Amazon CloudWatch, the monitoring layer. Lambda parses the alarm payload and extracts contextual metadata and then invokes the DevOps Agent with a structured investigation request.

Integration with Operational Excellence

This solution directly supports the AWS Well-Architected Framework’s Operational Excellence pillar by automating the investigation process and reducing the MTTR. The investigation capability of AWS DevOps Agent aligns with AWS Incident Detection and Response (IDR) best practices, helping teams to detect, diagnose, and develop mitigation plans for pipeline failures faster while maintaining a full audit trail of agent actions and findings. This creates a delivery pipeline that accelerates resolution workflows through automated diagnostics and actionable remediation recommendations, keeping deployments moving and engineering teams focused on building rather than firefighting.

Architecture diagram showing GitHub repository connected to AWS CodePipeline, CloudWatch, Lambda, and DevOps Agent in an automated investigation flow 

Figure 1: GitHub and DevOps Agent integration

Prerequisites 

For this walkthrough, you should have access to and understanding of the following:

  •  An AWS account with permissions to create AWS Identity and Access Management (IAM) roles:
    1. Agent Space role – for basic service operations.
    2. Agent Space web app role – for using the Agent Space web app functionality.
    3. (Optional) Secondary source account roles if monitoring multiple AWS accounts. Refer to the DevOps Agent user guide for the details on setting up these roles.
  • A GitHub account:
    1. You have a GitHub account with administrative permissions for your repositories, or an organization you belong to.
    2. Your repositories contain code that deploys to AWS resources you want to monitor.
    3. You have identified the GitHub repositories you want AWS DevOps agent to access.
  • Access to register DevOps Agent with your GitHub Account or Organization.
  • CloudWatch monitoring enabled for your application.

​​Implementation steps​ 

Note: For this blog we used a sample application  from the AWS-samples.

  1. ​​Create an AWS DevOps Agent Space and configure the webhook​
    The first step is to create a dedicated Agent Space that serves as the central hub for your automated investigation workflow. The Agent Space connects your monitoring infrastructure to the DevOps Agent’s analysis capabilities.
    Create the DevOps Agent space by following the steps outlined in the Getting Started with AWS DevOps Agent guide Navigate to the DevOps Agent console.
    Create an Agent Space named after your application (for example, `myhotelapp`)
    1) “Auto-create both IAM roles”.
    2) “Edit the role names to be descriptive (for example, DevOpsAgentRole-AgentSpace-hotel-app and DevOpsAgentRole-WebappAdmin-hotel-app)”
Screenshot of AWS DevOps Agent console showing the Agent Space creation interface with IAM role configuration options

Figure 2: Agent Spaces Screen

On the Capabilities tab, generate a webhook and save the credentials

Store the webhook credentials in AWS Secrets Manager:

```bash

aws secretsmanager create-secret \

--name devops-agent-webhook-credentials \

--secret-string '{"webhookUrl":"YOUR-WEBHOOK-URL","webhookSecret":"YOUR-WEBHOOK-SECRET"}' \

--region us-east-1

```

2. Configure GitHub integration with your AgentSpace

With your Agent Space created and webhook configured, the next step is to connect your GitHub repositories. This integration allows the DevOps Agent to access commit histories, pull request data, and code changes when investigating pipeline failures.

To configure GitHub integration with your AgentSpace:
1. From the Capabilities tab within your configured AgentSpace, navigate to the GitHub Configuration section and choose “Register”

Screenshot of the GitHub Configuration section in the AgentSpace Capabilities tab showing the Register button

Figure 3: Capability Providers

2.     Your GitHub repositories will be listed with their connection status.

3.     To connect to a repository, verify that the Status shows “Ready to connect” and choose the + button in the Actions column.

4.     Upon successful connection, the Status updates to ‘Connected’.

To automatically trigger AWS DevOps Agent investigations via Webhook when a CloudWatch enters the ALARM state, you can refer to sample-aws-devops-agent-cloudwatch and build based on your use case.

3. Troubleshooting application deployment 5XX errors with CloudWatch and AWS DevOps Agent

When your application encounters 5XX errors during deployment, CloudWatch alarms detect the anomaly and trigger the DevOps Agent investigation workflow. The following dashboard shows the alarm state that initiates the automated investigation process.

Screenshot of CloudWatch dashboard displaying alarm metrics triggered by application 5XX errors

Figure 4: CloudWatch Dashboard

4. Resolving deployment/build errors during CI/CD deployment

The following use cases demonstrate how AWS DevOps Agent investigates and resolves common CI/CD pipeline failures. Each scenario walks through the failure trigger, the automated investigation, and the remediation guidance that the agent provides

Use case 1: Push a code change that introduces an invalid DynamoDB table name

Simulate: Push a code change that breaks the DynamoDB table name — e.g., change DYNAMODB_TABLE_NAME env var but don’t update CloudFormation to make the CodePipeline unit testing fail

A – dynamodb_table: process.env.DYNAMODB_TABLE_NAME || “Rooms”,

B + dynamodb_table: “HotelRooms”

The CodePipeline triggers 5xx alarms and the webhook triggers a DevOps Agent investigation.

DevOps Agent analyzes the 500 errors in relation to the configuration change, identifies the invalid DynamoDB endpoint, and shows the timeline: configuration update → service redeployment → requests fail with connection errors.

Screenshot of CodePipeline execution view showing a failed unit test stage highlighted in red

Figure 5: Unit test failed for the CodePipeline

Use case 2: Identifying dependency resolution failures from bad commits

1. Navigate to `package.json`

2. Change any dependency name to something invalid — for example, change `”express”` to `”expresss”` (extra ‘s’)

3. Commit the change directly to `main`

CodePipeline detects the push and starts a new execution. The CI stage runs `npm install`, which fails because the misspelled package doesn’t exist. The Amazon EventBridge rule catches the stage failure and invokes the webhook executor Lambda, which triggers a DevOps Agent investigation.

In the DevOps Agent console, select your Agent Space, then choose Operator access to open the web app.  Navigate to the Incident Response tab to view the new investigation.

Screenshot of DevOps Agent showing the first step of the mitigation plan identifying the root cause

Figure 6: Mitigation plan step1

Screenshot of DevOps Agent showing steps 2 through 4 of the mitigation plan with remediation commands

Figure 7: Mitigation plan steps 2-4

DevOps Agent investigates the pipeline failure, examines the CodeBuild logs showing the `npm install` error, and correlates it with the recent commit to the repository. It identifies the root cause as a dependency resolution failure introduced by the latest code change.

Clean up

This walkthrough creates AWS resources that incur charges, including AWS DevOps Agent (pay-per-use), Lambda functions, CodePipeline executions, CloudWatch alarms, and Secrets Manager secrets. Follow the cleanup steps when finished to avoid ongoing charges.

1. Delete the Secrets Manager secret devops-agent-webhook-credentials using: aws secretsmanager delete-secret –secret-id devops-agent-webhook-credentials –region us-east-1

2. Delete your Agent Space from the AWS DevOps Agent console

3. Remove the GitHub pipeline connection from your settings.

4. Delete the IAM roles created for the Agent Space.

5. Delete the Lambda function, EventBridge rule, and CloudWatch alarms created for webhook integration.

6. (Optional) If you created additional source account roles, remove those as well.

Conclusion

The AWS DevOps Agent integration with GitHub fundamentally transforms how engineering teams approach CI/CD reliability by shifting from reactive troubleshooting to proactive incident prevention. By autonomously correlating CodePipeline failures with specific GitHub commits, analyzing root causes across the deployment chain, and providing intelligent remediation recommendations, this solution reduces mean time to resolution from hours to minutes while maintaining the human oversight necessary for production environments.

Organizations implementing this integration gain a resilient software delivery pipeline that combines the collaborative strengths of GitHub source control with AWS’s intelligent automation capabilities. This helps teams maintain deployment velocity, strengthen operational excellence, and focus engineering effort on innovation rather than incident response.

AWS CodePipeline, Amazon CloudWatch, AWS Lambda, and the AWS DevOps Agent integrate natively to provide end-to-end visibility and autonomous investigation capabilities. Together, they accelerate recovery workflows, reduce operational friction, and build the foundation for continuous delivery at scale.

About authors

Anjani Reddy

Anjani is a Sr. Solutions Architect at AWS. She works with Enterprise customers to provide operational guidance to innovate and build a secure, scalable cloud on the AWS platform. Outside of work, she is an Indian classical & salsa dancer, loves to travel and Volunteers for American Red Cross & Hands on Atlanta.

Jared Thompson
Jared Thompson is a Senior Technical Account Manager at AWS, where he partners with strategic enterprise customers to optimize cloud operations and accelerate AI/ML workloads at scale. Jared specializes in GPU-accelerated computing, capacity planning, and cloud observability, with a passion for turning complex infrastructure challenges into automated, self-healing systems. He is a recipient of the AWS Golden Jacket award and when not at work, he can be found on a cruise ship.

Aneesh Varghese is a Senior Technical Account Manager at AWS with more than 19 years of Information Technology industry experience. Aneesh supports enterprise customers in cost optimization strategies, Cloud operations, MLOps, providing advocacy and strategic technical guidance to help plan and build solutions using AWS best practices. Outside of work, Aneesh likes to spend time with family, play Basketball and Badminton.

Automate SageMaker HyperPod incident triage and root-cause-analysis with AWS DevOps Agent

Post Syndicated from Tomonori Shimomura original https://aws.amazon.com/blogs/devops/automate-sagemaker-hyperpod-incident-triage-and-root-cause-analysis-with-aws-devops-agent/

Introduction

Large-scale machine learning workloads: training, fine-tuning, and inference run on clusters of hundreds to thousands of GPU instances for days or weeks at a stretch. Keeping operational visibility across a fleet of this size is a constant challenge: hardware health events, node lifecycle transitions, capacity fluctuations, and workload-level issues appear in the event stream around the clock, including nights and weekends.

Amazon SageMaker HyperPod is a purpose-built managed cluster service that lets you run distributed model training, fine-tuning, and inference across hundreds of accelerated instances. It provides built-in resiliency that automatically detects and replaces faulty hardware, so long-running jobs can continue with minimal interruption.

For teams operating these clusters, the scale still creates a fundamental tension: you need continuous visibility into your fleet, but you can’t afford to keep engineers watching the event stream 24/7. 

What HyperPod resiliency already handles

SageMaker HyperPod’s built-in resiliency layer automatically detects and self-heals instance-level GPU failures. When the Health Monitoring Agent (HMA) identifies a bad GPU, the HyperPod resiliency layer drains, reboots, or replaces the node depending on the error type, and the job resumes without human intervention. This is exactly what you want: routine hardware failures are handled automatically so your training runs keep going. 

This solution does not replace HMA or any part of HyperPod’s resiliency. It adds an autonomous investigation layer on top, using the cluster events and health signals that HMA and HyperPod already produce as its input. 

Operational conditions where a human still wants to be in the loop 

With that self-healing in place, there are operational conditions where a human still wants to be in the loop or decide: 

  • Configuration issues: a lifecycle-script change you made, a misconfigured mount, or a networking/security change that causes provisioning failures on every new node. 
  • Capacity conditions: a replacement waiting on capacity in the pool, where the operator needs to know recovery is in flight and can decide whether to intervene. 
  • Recurring hardware faults: each fault self-heals correctly, but the same GPU error signature recurring across three or more replacements on one instance group in a week is a pattern worth surfacing to an operator as a single signal. 
  • Workload-level conditions: Pods stuck in CrashLoopBackOff for hours, nodes sitting NotReady, or GPU allocation chronically low. 

Without automation, these conditions push operators into round-the-clock manual triage: correlating events across the SageMaker control plane, Amazon EKS, and Amazon CloudWatch, and deciding whether HyperPod is still recovering or needs a hand. 

Opportunity: AWS DevOps Agent as a 24/7 companion 

AWS DevOps Agent provides an autonomous incident-response platform that can be taught a domain’s operational model through custom skills. By wiring your HyperPod cluster into DevOps Agent, you get a 24/7 companion that complements HyperPod’s self-healing. It watches for the operational conditions that still need a human decision, triaging them, root-causing them, and delivering a clear verdict with recommended actions. 

By design, DevOps Agent is configured to run in observe-and-report mode for this integration – it is not granted SSM, SSH, or action-taking permissions against your cluster or its nodes. The agent reads cluster events, control-plane state, Kubernetes objects, and CloudWatch logs to reconstruct what happened; every corrective action (node reboots, replacements, drains) continues to be performed by HyperPod’s own resiliency layer or by an operator responding to the emailed verdict. This read-only boundary is deliberate: it keeps the agent’s blast radius zero while still delivering the correlation and triage value. 

In this post, you will learn how to connect any SageMaker HyperPod cluster (either the EKS or Slurm Orchestrator option) to AWS DevOps Agent. Conditions are auto-detected, triaged, root-caused from cluster state and CloudWatch logs, and emailed as a clear verdict. You will also see how the solution can be extended to detect additional conditions specific to your workloads. 

Solution Overview 

What this solution delivers 

This solution wires any SageMaker HyperPod cluster into AWS DevOps Agent so that operational conditions calling for a human decision are auto-detected, triaged, root-caused, and delivered as a human-readable verdict email. Specifically, you get: 

  • Autodetection of HyperPod conditions that complement resiliency self-healing, from the live SageMaker event stream and a periodic Kubernetes-state audit. 
  • Triage + root-cause analysis by the DevOps Agent, taught HyperPod’s operational model via two custom skills. It reconstructs the incident timeline and decides whether HyperPod is still recovering or needs an operator. 
  • Human-readable verdict emails: Monitor (recovery in flight, here’s the ETA), Escalate (you need to act, here’s why and what to do), or Resolved (auto-recovery closed the loop). Noise is filtered out. 
  • Extensibility: customize what conditions are detected (by modifying the periodic-audit Lambda) and how the agent reasons about them (by editing the plain-English skills). 

The following screenshot shows the DevOps Agent incident response dashboard with example verdict emails for three common fault types: 

DevOps Agent incident response dashboard showing investigation list and timeline, with three email verdict examples for GPU NVLink fault, lifecycle-script bootstrap failure, and insufficient-capacity errors

DevOps Agent incident response dashboard showing investigation list and timeline, with three email verdict examples for GPU NVLink fault, lifecycle-script bootstrap failure, and insufficient-capacity errors

Architecture 

The whole solution deploys one AWS CloudFormation stack per cluster. Two event paths feed the DevOps Agent, and one path carries its verdicts back out to you. 

Architecture diagram showing the event flow from HyperPod Health Monitoring Agent through EventBridge to DevOps Agent and email notification

Architecture diagram showing the event flow from HyperPod Health Monitoring Agent through EventBridge to DevOps Agent and email notification

This architecture shows a 1:1 relationship between a HyperPod cluster and a DevOps Agent space, and the deployment instructions in this post follow that model. If you need to associate multiple clusters with a single Agent Space, you can customize the CloudFormation template and the ClusterFilter parameter to widen the allowlist of cluster names forwarded by the webhook bridge.

Event flow 

  1. Event-driven issue detection: HyperPod emits cluster-state, node-health, and capacity events to Amazon EventBridge. The webhook bridge Lambda drops routine Info-level noise, maps the rest into a DevOps Agent investigation payload, signs it with HMAC-SHA256 using a shared secret stored in AWS Secrets Manager, and POSTs it to the agent’s generic webhook. 
  1. Polling-based issue detection: A periodic-audit Lambda checks Kubernetes state (CrashLoopBackOff pods, NotReady nodes) every 15 minutes and fires only when it finds a real issue, plus a daily heartbeat confirming the pipeline is alive. On a healthy cluster, nothing is POSTed, so no investigation runs and no cost is incurred. 
  1. Investigation: DevOps Agent receives the payload and runs two custom skills: the triage skill decides whether to link (duplicate), skip (noise), or proceed (investigate). The RCA skill reconstructs the timeline using describe-cluster, list-cluster-nodes, list-cluster-events, kubectl, and CloudWatch logs (HMA health monitoring, lifecycle scripts), then classifies the incident as Suppress, Monitor, Escalate, or Resolved. 
  1. Notification: An Amazon Lambda function sends notification emails via Amazon SES. It listens on the aws.aidevops event stream for investigation completions, reads the verdict from the agent’s journal, and sends an email with the headline, what happened, likely cause, and recommended action. Suppress verdicts are filtered to avoid noise on healthy clusters. 

Getting started 

For a step-by-step walkthrough to deploy this solution, visit the DevOps Agent Integration guide. Once you have the solution running, the following sections explain how to customize detection, reasoning, and notifications for your environment. 

Prerequisites 

  • An AWS account with AWS CLI v2 configured for the target region. 
  • An existing SageMaker HyperPod cluster (EKS or Slurm orchestrator). 
  • IAM permissions to create roles, deploy CloudFormation, manage Secrets Manager, and call devops-agent:* and eks:CreateAccessEntry. 
  • For email notifications: a verified Amazon SES sender identity. You can verify an email address in the Amazon SES console or with the AWS CLI. After running the command below, the address owner will receive a verification email and must click the confirmation link:

    aws ses verify-email-identity --email-address [email protected]

    Recipients must also be verified if your SES account is still in sandbox mode. 

Deploying with CloudFormation

The solution deploys as a single CloudFormation stack. Clone the awsome-distributed-ai repository, create a params.json with your cluster name and email settings, and run: 

cd 1.architectures/5.sagemaker-hyperpod/tools/devops-agent

# 1. Set up a Python env with boto3 >= 1.43.25
python3 -m venv .venv && source .venv/bin/activate && pip install 'boto3>=1.43.25'

# 2. Fill in your cluster name and email addresses
cp deploy/params.example.json deploy/params.json
# edit: HyperPodClusterName, EmailSender, EmailRecipients 

# 3. Deploy
make deploy

This provisions the Agent Space with read-only EKS access (auto-discovered from the cluster’s orchestrator ARN), the EventBridge rule and webhook bridge Lambda, the periodic-audit scheduler, and the email notifier. For Slurm-orchestrated clusters, the EKS access step is skipped automatically. 

The webhook bridge — mapping HyperPod events to DevOps Agent 

An EventBridge rule captures HyperPod events and invokes a Lambda function. The Lambda forwards all Warn and Error level events, normalizing each into a DevOps Agent investigation payload. It extracts the failure message, instance group, and event metadata, then signs it with HMAC using a shared secret stored in AWS Secrets Manager, and POSTs it to the agent’s generic webhook endpoint. Info-level events are dropped at the bridge to avoid creating investigations for routine status updates. 

A cluster allowlist parameter lets you scope which HyperPod clusters trigger investigations, useful when multiple clusters share the same account and region. 

How the skills are defined — teaching the agent HyperPod’s operational model 

AWS DevOps Agent skills are plain-English instructions that teach the agent how to reason about a domain. This solution includes two complementary skills: 

Triage skill — LINKED / SKIPPED / PROCEED (view the skill document) 

The triage skill runs first on every incoming task. It decides whether to link the event to an existing investigation, skip it, or proceed to a full investigation. 

  • Why triage matters — a concrete example: When a single node fails, HyperPod’s replacement process emits multiple events in quick succession: “lost orchestration-ready status,” “provisioning started,” “capacity request initiated.” Without triage, each event would spawn a separate investigation. The triage skill recognizes these events belong to the same incident (same instance group + overlapping time window) and links them, so only one investigation runs. This saves investigation compute and avoids duplicate emails. 
  • When to SKIP: When a node is already being replaced and a follow-up “lost orchestration-ready status” event arrives with a generic “Request to service failed” message, the triage skill recognizes that a replacement is already in progress for that instance group and skips the event. No new investigation is created for what is simply a progress update of an existing recovery. 

RCA skill — timeline reconstruction and verdict (view the skill document) 

When triage produces PROCEED, the RCA skill takes over. It reads cluster state, events, and logs, reconstructs an incident timeline, and classifies the situation into one of four verdicts:

 RCA Flowchart showing the four phases of root-cause analysis: data gathering, timeline reconstruction, classification, and recurrence check

RCA Flowchart showing the four phases of root-cause analysis: data gathering, timeline reconstruction, classification, and recurrence check

  • Phase 1 — Data gathering: The skill reads describe-cluster, list-cluster-nodes, list-cluster-events, and CloudWatch log streams (HMA health monitoring, lifecycle scripts) to collect the raw facts. 
  • Phase 2 — Timeline reconstruction: It orders events chronologically and identifies the fault chain: what triggered what, which nodes were affected, and what recovery actions HyperPod took. 
  • Phase 3 — Classification: Based on the timeline, recurrence statistics, and HyperPod’s resiliency behavior, it assigns a verdict: 
    • Suppress — a non-issue (for example, a transient event that has already resolved). 
    • Monitor — recovery is in flight; here’s the expected resolution window. 
    • Escalate — you need to act; here’s the root cause and recommended action. 
  • Resolved — auto-recovery closed the loop; no action needed. 
  • Phase 4 — Recurrence check: The skill computes sliding-window statistics over the one week cluster event history. When thresholds are crossed, the verdict escalates to alert the operator of a systemic pattern. For example, the same GPU error signature on the same instance group three or more times in a week, or five or more replacements fleet-wide in 24 hours. 

The verdict is written to the agent’s investigation journal along with a human-readable report containing what happened, the likely cause, and recommended operator actions. 

The periodic-audit Lambda — Kubernetes state monitoring 

The periodic-audit Lambda fires every 15 minutes and inspects Kubernetes Pod/Node state directly (via the EKS API server). It checks for: 

  • Pods in CrashLoopBackOff (default: flagged when restart count reaches five and the last crash is within 15 minutes) 
  • NotReady nodes (default: flagged when a node has been NotReady for at least 15 minutes and at least 10% of nodes are affected) 

Namespace-aware filtering controls which pods are checked: 

  • Pods in kube-public and kube-node-lease are ignored entirely by default. 
  • Pods in kube-systemaws-hyperpod, and amazon-cloudwatch are tagged as system-workload issues (distinct from user-workload issues in the verdict). 

All thresholds and namespace lists are configurable via the CloudFormation stack parameters. 

The Lambda POSTs a webhook event to DevOps Agent only when a real issue is found. On a healthy cluster, nothing is POSTed, so no investigation runs and no cost is incurred. A separate daily heartbeat schedule confirms the monitoring pipeline itself is alive. The heartbeat is visible in the DevOps Agent console but deliberately not emailed on healthy runs — so silence in your inbox means the cluster is healthy, not that the pipeline is broken. 

Note: HyperPod infrastructure faults (node health, capacity errors, lifecycle-script failures) are handled event-driven by the webhook bridge. They come from the native HyperPod event stream in EventBridge. The periodic audit deliberately does not duplicate that path; it only covers Kubernetes workload state, which is not in the HyperPod event stream. 

Closing the loop — the email notifier

An EventBridge rule on the aws.aidevops event stream captures investigation lifecycle events. The email-notifier Lambda processes these events through the following steps: 

  1. Event filtering: Only “Investigation Completed” events are processed (one email per investigation lifecycle). The event payload contains the agent_space_id, task_id, and execution_id. 
  2. Dedup: The Lambda checks an S3 marker at s3://<bucket>/emailed/<execution_id>. If present, this investigation has already been emailed and the event is dropped. This prevents duplicate emails when the same completion event is re-emitted. 
  3. Fetching the investigation context: The Lambda calls two DevOps Agent APIs: 
    • get_backlog_task(agentSpaceId, taskId) — retrieves the task metadata (title, priority, timestamps). 
    • list_journal_records(agentSpaceId, executionId) — retrieves the investigation’s findings, symptoms, and investigation gaps from the agent’s journal. 
  4. Suppress-verdict filtering: If the investigation produced a Suppress verdict or no findings at all, no email is sent. 
  5. Email composition: The Lambda composes a single HTML email from the journal records: a short headline followed by a one-paragraph summary covering what happened, the likely cause, and the recommended action. 
  6. Send via SES: The formatted email is sent to the configured recipients. After successful delivery, the S3 dedup marker is written. 

The operator also has access to the full investigation in the DevOps Agent web console (see following “Viewing investigations” section). 

Viewing investigations in the DevOps Agent console 

For readers new to AWS DevOps Agent, here’s how to navigate to your investigations: 

  1. Open the AWS DevOps Agent console. 
  2. Select your Agent Space (named hyperpod-<cluster-name>-devops-agent by default). 
  3. From the Launch web app drop-down, choose an option to open the DevOps Agent web app. 
  4. Select Incidents from the left navigation pane to open the Incident Response Dashboard. It lists all investigations with their subject, status, and timestamp. 
  5. Select any investigation to see its full timeline, journal records, and the verdict report. 

Asking the agent directly — the DevOps Agent Chat UI 

Beyond the automated emails, you don’t have to wait for the next investigation to get answers about your cluster. You can open the DevOps Agent’s AI chat at any time and ask follow-up questions in plain English. The agent answers from the live cluster state, the investigation history, and the skills it has been taught. 

For example: 

  • “I got an email about a GPU failure in my cluster. Did it get resolved now with HyperPod’s resiliency?” — The agent checks the current cluster state, confirms whether the replacement succeeded, and provides a timeline of what happened (HMA detection  replacement initiated  node back in service), along with anything to watch for. 
  • “Are there unhealthy Pods on my cluster?” — The agent inspects the Kubernetes state and reports any CrashLoopBackOff pods or NotReady nodes. 
  • “I just triggered scaling up. Check if it is progressing well.” — The agent looks at the cluster’s current node counts vs. target counts and reports whether provisioning is on track. 
AWS DevOps Agent chat interface showing a natural language query about cluster health

AWS DevOps Agent chat interface showing a natural language query about cluster health

The chat conversations are stored per Agent Space, so you can revisit past interactions alongside the automated investigations. This makes the Agent Space a single pane of glass for both automated incident response and ad-hoc troubleshooting of your HyperPod cluster. 

Extending the solution — detection vs. reasoning 

The solution has two extension points, which serve different purposes: 

  1. Extending detection (what conditions are caught): 
    • Event-driven path: The webhook bridge Lambda drops Info-level events and forwards all Warn and Error level HyperPod events to DevOps Agent. This typically does not need modification. It already catches all actionable events. 
    • Polling-based path: The periodic-audit Lambda checks Kubernetes state. To detect additional conditions (for example, GPU allocation below a threshold or specific Pod labels stuck in error states), add that logic to the Lambda code. 
  2. Extending reasoning (how the agent investigates and classifies): edit the plain-English skill definitions. For example, you can teach the RCA skill new classification rules, add domain-specific context about your workload’s expected behavior, or adjust the recurrence thresholds. 

Detection is code; reasoning is natural language. Both are in the repo and designed to be customized independently. 

Investigation feedback 

After each investigation completes, a Feedback button appears in the DevOps Agent console. Clicking it opens the Investigation feedback dialog, where you can: 

  • Rate whether the root cause was correct 
  • Indicate whether human steering was needed during the investigation 
  • Provide written feedback explaining what could be improved 

This structured feedback is stored per investigation. An auto-learning mechanism that uses this feedback to improve future investigations is actively being developed. 

DevOps Agent APIs used by this solution 

For readers interested in the programmatic integration, here are the key DevOps Agent APIs this solution calls:

Component API Purpose
Webhook provisioner (deployment) register_service Register the generic webhook service with DevOps Agent
Webhook provisioner (deployment) associate_service Associate the webhook with the Agent Space
Skill uploader (deployment) list_assets Check if a skill already exists
Skill uploader (deployment) create_asset / update_asset Upload or update the triage and RCA skill definitions
Email notifier (runtime) get_backlog_task Retrieve task metadata (title, priority, timestamps)
Email notifier (runtime) list_journal_records Retrieve findings, symptoms, and gaps from the investigation journal
Teardown disassociate_service / deregister_service / delete_asset Clean up on stack deletion

Cleaning up 

To remove all resources created by this solution, run: 

make teardown-stack

This deletes the CloudFormation stack, removes the Agent Space, EKS access entries, secrets, and email configuration.

Additionally, if you no longer need the prerequisite resources, you can revert their setup, for example, deleting the verified Amazon SES email address identities you created for notifications.

Cost considerations 

This solution is designed to be near-zero cost on a healthy cluster and scales proportionally with fault volume. Cost scales with fault volume, not node count directly. At large scale (100+ nodes), the triage skill becomes critical. A single hardware fault can generate 5-10 correlated EventBridge events, most of which are filtered by the webhook bridge Lambda before reaching the agent. Where triage adds value is linking and deduplicating across similar faults that affect multiple instances, or repeated faults on the same instance over time, consolidating them into a single investigation instead of many. As an example, a 500-node training cluster might see 20-50 investigations per month after filtering and deduplication. 

  1. Filtering and triage are your cost savers at scale. The webhook bridge filters correlated events from a single node failure (5-10 EventBridge events reduced to 1 forwarded event), eliminating redundant investigations at the source. Triage then links similar faults across multiple instances into a single investigation. For example, if 5 nodes hit the same GPU error in a window, triage consolidates them into 1 investigation instead of 5 (saving 4 × $4 = $16). The bigger the cluster, the more both layers save. 
  2. Investigation duration grows sub-linearly. A 1000-node cluster investigation doesn’t take 100x longer than a 10-node one. The agent queries describe-cluster and list-cluster-events once regardless of size. The data returned is bigger, but the API call count is similar. 
  3. CloudWatch Logs queries are the variable. On large clusters, the agent may query more HMA log streams, which takes longer agent-seconds AND incurs CloudWatch Logs Insights charges on your account (not part of DevOps Agent pricing). 

DevOps Agent (the primary cost driver): Estimates based on 2 accelerator instances in a cluster 

Component Pricing Your cluster estimate
Investigations $0.0083/agent-second ~$4/investigation (at 8 min avg)
Chat (on-demand SRE tasks) $0.0083/agent-second ~$0.25/chat query (at 30 sec avg)
Daily heartbeat $0.0083/agent-second ~$1-2/day (short investigation confirming health)

On a healthy cluster with no faults, only the daily heartbeat fires, approximately $30-60/month in DevOps Agent time. On a cluster experiencing 5 real faults per week (typical for a large GPU fleet), expect ~20 investigations/month × $4 each = $80/month in investigation costs.

Free tier and credits:

New DevOps Agent customers receive a 2-month free trial (20 hours of investigations, 20 hours of chat per month). Enterprise Support customers receive monthly credits equal to 75% of their AWS Support charge toward DevOps Agent usage. 

Supporting infrastructure (secondary costs): 

Component Monthly Cost Estimates
Lambda invocations ~96/day (15-min audit) + event-driven = well within free tier
S3 (skills + dedup markers) < $0.01 (a few MB total)
Secrets Manager (1 secret) $0.40
EventBridge rules Negligible (per-event pricing)
SES emails $0.10/1000 emails — at most 1 per investigation
CloudWatch Logs (Lambda) < $1 (minimal log volume)

Total estimated monthly cost: 

Scenario DevOps Agent Infrastructure Total
Healthy cluster (no faults) ~$30-60 (heartbeat only) < $2 ~$32-62/month
Moderate faults (5/week) ~$80-120 < $2 ~$82-122/month
Heavy faults (20/week) ~$320-400 < $5 ~$325-405/month

How cluster size impacts cost 

Factor Small cluster (1-10 nodes) Large cluster (100-1000 nodes)
Fault frequency Rare (maybe 1-2/week) Constant (NVIDIA reports ~1 fault/2-3 hours at 10K GPU scale)
Events per fault Few (1 node replacement = 3-5 events) More (cascading replacements, capacity queuing)
Investigation duration Shorter (less state to read, fewer events in timeline) Longer (more nodes to describe, more events to correlate, larger CloudWatch log groups to query)
Triage value Low (few duplicates) High (one fault generates many correlated events — triage links them into 1 investigation)
Periodic audit Fast (few pods/nodes to check) Slower (more K8s state to inspect)
Cluster Size Faults/month Investigations Est. Agent Cost
1-10 nodes (your test) 2-5 2-5 + heartbeat $8-20/mo + ~$30 heartbeat
10-50 nodes (typical prod) 5-20 5-15 (triage dedup) $20-60/mo + ~$30 heartbeat
100-500 nodes (large training) 50-200 20-50 (heavy triage) $80-200/mo + ~$45 heartbeat
1000+ nodes (frontier) 200-700 50-100 (massive dedup) $200-500/mo + ~$60 heartbeat

Cost control levers: 

  1. Disable the periodic audit (EnablePeriodicAudit: false) to eliminate the heartbeat cost. Live event bridging still works. 
  2. Triage (LINK/SKIP decisions) runs at task creation time. No investigation cost is billed for deduplicated or skipped events. 
  3. Suppress verdicts filter email notifications but the investigation still runs. If you want to eliminate that cost, tune your EventBridge rule to drop more event types at the bridge level. 

Comparison to manual monitoring: 

Without automation, each fault requires an on-call engineer to manually correlate events across CloudWatch, EKS, and the SageMaker console, typically 30-45 minutes of triage before they even know whether HyperPod is self-healing or needs intervention. This solution delivers a root-caused verdict in minutes at ~$4 per investigation, while providing 24/7 coverage without human wake-ups. The cost savings compound with cluster scale: at 20 faults per month, that’s 10-15 hours of engineering triage replaced by automated verdicts. 

Conclusion 

In this post, we showed how to build an end-to-end agentic incident-response pipeline for SageMaker HyperPod using AWS DevOps Agent. The solution complements HyperPod’s built-in resiliency by watching for the operational conditions where a human still wants to be in the loop: configuration issues affecting provisioning, capacity-bound recoveries, recurring hardware fault patterns, and workload-level conditions. It delivers clear, root-caused verdicts to the operator’s inbox. 

The broader takeaway is a reusable pattern: teaching an AI agent a domain’s operational model through plain-English skills, so it can distinguish “the system is recovering on its own” from “this needs a human decision.” This pattern applies beyond HyperPod to any event-driven AWS service where operational conditions benefit from automated correlation and triage. 

What’s next 

To deploy the solution, follow the step-by-step instructions in the DevOps Agent Integration guide on the AI on SageMaker HyperPod site. Once it’s running, you can customize it for your environment: 

  • Adjust the CloudFormation parameters: tune the periodic-audit schedule, CrashLoopBackOff thresholds, NotReady node percentages, namespace filtering, and email recipients. No code changes required. 
  • Extend detection: modify the periodic-audit Lambda to check for additional Kubernetes conditions specific to your workloads (for example, GPU allocation below a threshold, specific Pod labels stuck in error states). 
  • Extend reasoning: edit the triage or RCA skill definitions to adjust classification rules, add domain context about your expected cluster behavior, or tune the recurrence thresholds. 
  • Add notification channels: connect Slack or PagerDuty via DevOps Agent’s built-in integrations or via a sibling EventBridge rule on the same aws.aidevops event stream. 

The skills are plain English. Iterate on them the same way you’d iterate on a runbook. 

About the authors

Tomonori Shimomura is a Principal Solutions Architect on the Amazon SageMaker AI team, where he provides in-depth technical consultation to SageMaker AI customers and suggests product improvements to the product team. Before joining Amazon, he worked on the design and development of embedded software for video game consoles, and now he leverages his in-depth skills in Cloud side technology. In his free time, he enjoys playing video games, reading books, and writing software.

Mayank Gupta is a Senior AI/ML Specialist with deep expertise in machine learning frameworks and enterprise AI architecture. He brings strong hands-on experience with AWS AI services, including SageMaker AI and SageMaker AI HyperPod, and leads the design and delivery of end-to-end AI solutions spanning model development, distributed training, and production-scale deployment. With deep experience in performance optimization and scalable ML architectures, Mayank partners with customers to translate complex business challenges into secure, high-impact, production-ready AI systems that drive measurable outcomes.

Deepthi Madamanchi is a Principal Technical Account Manager at AWS focused on AI Models, where she leads frontier AI segment through building and operating multi-thousand-node GPU clusters for foundation model training and inference. She specializes in distributed training, high-throughput networking, GPU fleet optimization, Amazon Bedrock adoption, helping them optimize performance, reliability, and cost efficiency from experimentation through production. In her free time, Deepthi explores functional health, experiments with new recipes, and travels with her family.

Dushyant Dubaria is a Senior Technical Account Manager on the AWS Frontier AI Startup team, where he supports frontier AI model builder companies deploying and operating large-scale GPU training infrastructure on Amazon SageMaker HyperPod and Amazon EKS. He specializes in distributed training orchestration, storage at petabyte scale (Amazon FSx for Lustre, Amazon S3), high-throughput networking, and operational resilience including cluster health monitoring, capacity planning, and proactive incident management for multi-thousand-node clusters. He helps organizations achieve reliable, high-performance ML workloads from initial cluster deployment through sustained production training. In his free time, he enjoys building automation tools, exploring new AI technologies, and playing cricket.

Shreyas Adiyodi is a Product Manager at AWS based out of Seattle. He is focused on enabling Gen AI model development on SageMaker HyperPod, partnering with customers to simplify cluster provisioning, accelerate foundation-model training, and strengthen security and compliance. Outside of work, he enjoys chess, MMA and watching movies.

Scaling Autonomous Operations with AWS DevOps Agent and ServiceNow

Post Syndicated from Jack Hwang original https://aws.amazon.com/blogs/devops/scaling-autonomous-operations-with-aws-devops-agent-and-servicenow/

This post is co-written with Govind Menon, Head of MCP Product at ServiceNow.

Introduction

Enterprise teams managing applications on AWS often rely on ServiceNow as their IT service management (ITSM) system for incident tracking, change management, and configuration management. When incidents occur, engineers must context-switch between AWS, third party observability tools and ServiceNow, manually correlating data across those sources before updating ServiceNow incident records. This fragmented workflow delays resolution, increases mean time to resolution (MTTR), and introduces the risk of missed signals.

AWS DevOps Agent is a frontier agent that resolves and proactively helps prevent incidents, continuously improving reliability and performance of applications in AWS, and hybrid environments. In this post, we demonstrate how to integrate AWS DevOps Agent with ServiceNow using the Model Context Protocol (MCP) and ServiceNow Action Fabric, enabling autonomous incident investigation and resolution workflows that are governed by ServiceNow and that execute and record authorized actions directly on the application.

By the end of this post, you will be able to:

  • Configure AWS DevOps Agent as an MCP client connecting to ServiceNow MCP Server created in the MCP Server Console
  • Authenticate securely via OAuth 2.0 between AWS DevOps Agent and ServiceNow
  • Enable dynamic discovery of ServiceNow tools exposed through Action Fabric and governed through the ServiceNow MCP Server Console
  • Automate root cause analysis directly within ServiceNow incidents

Integrating ServiceNow MCP Server with AWS DevOps Agent

The integration between ServiceNow MCP Server and AWS DevOps Agent connects ITSM workflows with automated incident response through the Model Context Protocol (MCP), an open standard for AI agent-to-tool communication.

ServiceNow MCP Server Console lets you create a ServiceNow MCP Server and configure the tools it exposes, capabilities such as incident management, CMDB queries, and change requests as discoverable tools. The console governs what the agent can see and do through tool-level scoping, access control lists, and role masking. It is the access channel for ServiceNow Action Fabric, the application’s governed action layer: ServiceNow does not merely store the agent’s output, it controls and executes the actions the agent is authorized to perform.

AWS DevOps Agent acts as an MCP client that dynamically discovers available ServiceNow tools at runtime. You can create tools based on existing capabilities, such as ServiceNow NowAssist Skills.

When a ServiceNow incident triggers AWS DevOps Agent, the following happens:

  1. Correlates telemetry from Amazon CloudWatch, deployment data, and code changes
  2. Discovers available ServiceNow tools through the ServiceNow MCP Server
  3. Queries ServiceNow for related incidents, change records, and CMDB context
  4. Identifies root cause by correlating AWS telemetry with ServiceNow operational data
  5. Writes findings, root cause analysis, and mitigation plans directly into the ServiceNow incident
  6. Executes governed actions on the application (for example, creating a change request) through the tools the ServiceNow MCP Server Console exposes, where authorized

Security is built into every interaction. Communication uses OAuth 2.0 authentication with scoped

Permissions. The ServiceNow MCP Server Console governs which tools the agent can access and what actions it can perform, with every invocation authenticated, authorized at the tool and skill level, and recorded in an auditable trail that ServiceNow AI Control Tower can observe.

AWS DevOps Agent connecting to ServiceNow via MCP Server with OAuth 2.0

Figure 1: Integration architecture showing AWS DevOps Agent connecting to ServiceNow via MCP Server

Prerequisites

Before you begin, make sure you have access to and understanding of the following:

  • An AWS account with permissions to create AWS Identity and Access Management (IAM) roles:
  • Created AWS DevOps Agent Space role and Web app role
  • Access to AWS DevOps Agent
  • A ServiceNow instance with admin access
  • ServiceNow MCP Server configured and accessible ServiceNow MCP Server configured and accessible on an AI Native subscription (Foundation, Advanced, or Prime) or via the standalone MCP add-on

Step 1: Configure the ServiceNow MCP Server and its Tools in the MCP Server Console

As first step, configure the ServiceNow instance to expose capabilities through the MCP Server:

  1. Navigate to the MCP Server Console in the ServiceNow Instance
  2. Create a new MCP Server (or select the MCP server provisioned).

MCP Server Console in a ServiceNow instance

Figure 2: MCP Server Console in ServiceNow Instance 

  1. Add Tools for the capabilities the agent needs (for example, incident read and update, CMDB query, change request creation), and scope each with ACLs and role masking so the agent can perform only authorized actions.

Tool selection in the ServiceNow MCP Server Console

Figure 3: Tool selection in ServiceNow MCP Server

  1. Configure inbound authentication for the MCP Server.

Create Inbound Integration dialog with OAuth Client Credentials grant

Figure 4: Create Inbound Integration – OAuth Client Credentials grant

Step 2: Create and configure a DevOps Agent Space

Create an AWS DevOps Agent Space in your AWS account to define the scope of resources the agent will monitor and investigate:

  1. Access the AWS DevOps Agent console
  2. Choose Create Agent Space and provide a name and description, and configure the required IAM roles (automated or manual setup)

Create Agent Space workflow in the AWS DevOps Agent console

Figure 5: Creating an Agent Space in the AWS DevOps Agent console

Agent Space name and IAM role configuration

Figure 6: Agent Space Name and IAM role configuration

  1. Confirm creation of AWS DevOps Agent Space.

Step 3: Register ServiceNow MCP Server in the AWS DevOps Agent console

Register your ServiceNow MCP Server connection to enable tool discovery in the AWS DevOps Agent console.

  1. Navigate to Capability Providers in the AWS DevOps Agent console. Under MCP Server, select Add source, then Register New MCP Server.
  2. Enter your ServiceNow MCP Server endpoint URL:https://<instance>.service-now.com/sncapps/mcp-server/mcp/<server_label>

Register MCP Server dialog with ServiceNow endpoint URL

Figure 7: Entering the ServiceNow MCP Server endpoint URL

  1. Select OAuth Client Credentials as the authorization flow. Enter the Client ID, Client Secret, and Exchange URL (https://<instance>.service-now.com/oauth_token.do) from Step 1.

OAuth Client Credentials form with Client ID, Client Secret, and Exchange URL

Figure 8: OAuth Client Credentials configuration for the ServiceNow MCP Server

  1. Submit the registration. AWS DevOps Agent validates the connection and discovers available tools. Select the tools to add to your Agent Space.

Selecting discovered ServiceNow MCP tools to add to the Agent Space

Figure 9: Selecting ServiceNow MCP tools to add to the Agent Space

  1. Confirm the MCP Server is associated and tools are connected.

Putting It All Together: End-to-End Test

Once the setup is complete, we need to make sure the connection is working.

  1. Navigate to Operator Access in the AWS DevOps Agent Space.
  2. Open a new chat window, and type “Can you show me all the incident in the past week from ServiceNow”
  3. Make sure the Agent calls the ServiceNow tools and shows the right results.

Testing the ServiceNow MCP connection by querying recent incidents

Figure 10: Test the ServiceNow MCP connection from AWS DevOps Agent

You can also configure your environment so that the creation of an incident in ServiceNow automatically triggers the AWS DevOps Agent. To set up this integration, follow the AWS documentation to establish the connection between AWS DevOps Agent and your ServiceNow instance. Then, create a Business Rule in ServiceNow. This enables incident creation to seamlessly trigger the DevOps Agent without manual intervention.

Once this setup is complete, here’s how the workflow comes together: when an incident is created, the DevOps Agent automatically investigates and adds relevant context such as root cause analysis, related changes, and affected resources directly back into the incident record. This means that by the time your Operations or SRE team picks up the incident, they already have the context they need to begin resolution, significantly reducing triage time and accelerating mean time to recovery (MTTR).

ServiceNow console showing investigation kick off

Figure 11: AWS DevOps Agent initiating an automated investigation on the ServiceNow incident

ServiceNow console investigation complete

Figure 12: AWS DevOps Agent mitigation plan posted to the ServiceNow incident

Clean up

To avoid incurring ongoing costs, clean up your resources when you are done using the integration. For details on pricing, visit the AWS DevOps Agent pricing page.

When you are done using the integration, clean up your resources:

  1. Delete your Agent Space from the AWS DevOps Agent console
  2. Remove the ServiceNow MCP Server connection from your settings
  3. Delete the IAM roles created for the Agent Space
  4. (Optional) Disable the MCP Server configuration in your ServiceNow instance

Conclusion

For organizations running workloads on AWS and managing operations through ServiceNow, incident response has long meant toggling between systems and racing to document findings before context fades. The integration between AWS DevOps Agent and ServiceNow through MCP and Action Fabric alleviates that gap. The agent investigates autonomously, correlates telemetry with operational context, and documents root cause and mitigation directly in the incident record, compressing resolution times from hours to minutes.

And because the connection is built on MCP, an open protocol for agent-to-tool communication, what you configure today continues to expand as your ServiceNow workflows evolve. New tools exposed through Action Fabric are discovered and available to the agent immediately. To get started, visit the AWS DevOps Agent product page and ServiceNow MCP Server Console page.

Arunsingh Jeyasingh Jacob

Arunsingh Jeyasingh Jacob

Arunsingh Jeyasingh Jacob is a Senior Solutions Architect at AWS. He’s passionate about solving business and technology challenges as an AWS customer advocate, with his recent interest being AI strategy. When not at work, Arun enjoys listening to podcasts, going for short trail runs, and spending quality time with his family.

Govind Menon

Govind Menon

Govind Menon is the Head of MCP Product at ServiceNow. He is a Carnegie Mellon alum with a passion for building impactful products. Outside work, he orchestrates annual mystery trips for friends and hosts a one-day adaptations of CBS’s Survivor in San Francisco.

Jack Hwang

Jack Hwang

Jack Hwang is an Associate Solutions Architect at AWS, where he works with ISVs to design and optimize their workloads on AWS with a passion for AI innovation. Outside of work, Jack enjoys going for a run and spending time with his cat, Casper.

Accelerate CloudFormation development with the IaC MCP Server

Post Syndicated from Shuto Yukawa original https://aws.amazon.com/blogs/devops/accelerate-cloudformation-development-with-the-iac-mcp-server/

Organizations adopt Infrastructure as Code (IaC) to manage cloud environments reliably, repeatably, and at scale. As teams grow and infrastructure complexity increases, IaC becomes the backbone of consistent deployments, compliance enforcement, and operational agility. The developer’s experience around IaC, however, remains fragmented — engineers routinely context-switch between documentation portals, linting tools, deployment consoles, and logging systems just to complete a single deploy cycle. This friction compounds across teams: slower iteration means delayed feature releases, longer incident recovery times, and increased operational risk. When a deployment fails, diagnosing the root cause across disconnected interfaces can take longer than writing the template itself — turning a feedback loop that could take hours of manual investigation into a more streamlined process.

The AWS Infrastructure as Code (IaC) MCP Server brings AWS CloudFormation documentation search, template validation, and deployment troubleshooting into your AI assistant, so you can move through a full AWS CloudFormation development cycle without leaving the chat interface. Developing AWS CloudFormation templates often means switching between documentation pages, linters, the deployment console, and AWS CloudTrail Logs. Each context switch adds friction to the inner development loop — the tight cycle of writing, validating, deploying, and fixing infrastructure code. This fragmented workflow increases time-to-deployment, delays feedback, and reduces developer productivity, particularly for teams managing complex, multi-resource stacks at scale.

The AWS Infrastructure as Code (IaC) Model Context Protocol (MCP) Server unifies these capabilities in one place. This post demonstrates how the IaC MCP Server tools work together in a real workflow — from authoring and validation through deployment and runtime troubleshooting — all within a single AI assistant conversation.

In this post, you can move through a complete CloudFormation development cycle using your AI assistant. You generate a template for an Amazon Simple Storage Service (Amazon S3) bucket, an AWS Lambda function, an AWS Identity and Access Management (IAM) execution role, and an Amazon CloudWatch Logs log group. You then validate, deploy, diagnose a deployment failure, and redeploy, all in a single interface.

Solution overview

The walkthrough follows four steps that map to IaC MCP Server tools:

  1. Author: Search CloudFormation documentation and generate a template
  2. Validate: Check syntax with cfn-lint and compliance with cfn-guard
  3. Deploy: Deploy the stack using a CloudFormation service role
  4. Troubleshoot: Diagnose a deployment failure using CloudTrail correlation

Figure 1 shows the four-step workflow. Steps 1, 2, and 4 run inside the IaC MCP Server, while Step 3 uses the AWS CLI directly.

Architecture diagram showing the end-to-end CloudFormation workflow. You send a prompt to your AI assistant. Inside the AI assistant, the IaC MCP Server handles Step 1 (Author using search_cloudformation_documentation), Step 2 (Validate using cfn-lint and cfn-guard), and Step 4 (Troubleshoot using stack events and CloudTrail). Step 3 (Deploy) runs outside the IaC MCP Server using the AWS CLI with a CloudFormation service role.

Figure 1. End-to-end CloudFormation workflow with the IaC MCP Server

In the prerequisites, you deploy a CloudFormation service role stack that deliberately omits the iam:PassRole permission. During the walkthrough, you use the AI assistant to generate and deploy an application stack. When CloudFormation tries to assign the Lambda execution role, the deployment fails with AccessDenied. The troubleshoot tool then correlates stack events with CloudTrail to pinpoint the root cause.

For an introduction to each IaC MCP Server tool, see Introducing the AWS Infrastructure as Code MCP Server.

Prerequisites

Before you start the walkthrough, set up your AWS account and AI assistant and deploy the service role stack that the walkthrough depends on.

To follow along, you need:

This walkthrough uses the us-east-1 Region. You can use a different Region, but make sure to use the same Region consistently across each step.

Clone the companion repository and deploy the service role stack:

git clone https://github.com/aws-samples/sample-accelerate-cloudformation-with-iac-mcp-server.git

cd sample-accelerate-cloudformation-with-iac-mcp-server

aws cloudformation deploy \
  --template-file iac-mcp-blog-role-stack.yaml \
  --stack-name iac-mcp-blog-role-stack \
  --capabilities CAPABILITY_NAMED_IAM

This role grants CloudFormation permission to create S3 buckets, Lambda functions, and CloudWatch Logs log groups, but deliberately omits iam:PassRole — you’ll diagnose this gap in Step 4.

You use the --capabilities CAPABILITY_NAMED_IAM flag to acknowledge that the stack creates IAM resources with custom names.

We provide this role template for demonstration purposes only and do not intend it for production use.

Note the role ARN from the stack outputs. You must use this ARN in Step 3:

aws cloudformation describe-stacks \
  --stack-name iac-mcp-blog-role-stack \
  --query "Stacks[0].Outputs[?OutputKey=='ServiceRoleArn'].OutputValue" \
  --output text

Walkthrough

The four steps that follow map to IaC MCP Server tools: authoring with documentation search, validating with cfn-lint and cfn-guard, deploying with a CloudFormation service role, and troubleshooting with CloudTrail correlation.

Step 1: Generate a CloudFormation template

Start by asking your AI assistant to search CloudFormation documentation and generate a template. The IaC MCP Server calls the search_cloudformation_documentation tool behind the scenes to retrieve up-to-date resource property references.

Prompt:

Create a CloudFormation template with an S3 bucket, a Lambda function (Python 3.13 runtime, inline hello-world code), an IAM execution role for the function, and a CloudWatch Logs log group. Include common security configurations. Save it as iac-mcp-blog-app-stack.yaml in the current directory.

The AI assistant calls the search_cloudformation_documentation tool to look up resource properties for AWS::S3::Bucket, AWS::Lambda::Function, AWS::IAM::Role, and AWS::Logs::LogGroup. You can see the tool invocations in Kiro’s chat interface. The search results include up-to-date property references and example configurations, which the AI assistant uses to generate a template.

The generated template should include resources similar to the following (your output may vary):

  • An S3 bucket with versioning, encryption, and public access block
  • A Lambda function with inline Python code
  • An IAM role with a least-privilege policy for CloudWatch Logs
  • A log group with a retention policy

The following snippet shows the key resources. Your AI assistant’s output may differ in naming or structure, but the core configuration should be similar:

Resources:
  S3Bucket:
    Type: AWS::S3::Bucket
    Properties:
      BucketEncryption:
        ServerSideEncryptionConfiguration:
          - ServerSideEncryptionByDefault:
              SSEAlgorithm: AES256
      PublicAccessBlockConfiguration:
        BlockPublicAcls: true
        BlockPublicPolicy: true
        IgnorePublicAcls: true
        RestrictPublicBuckets: true
      VersioningConfiguration:
        Status: Enabled

  LambdaFunction:
    Type: AWS::Lambda::Function
    Properties:
      Runtime: python3.13
      Handler: index.handler
      Role: !GetAtt LambdaExecutionRole.Arn
      Code:
        ZipFile: |
          def handler(event, context):
              return {"statusCode": 200, "body": "Hello from Lambda!"}

Step 2: Validate the template

Before deploying, ask the AI assistant to validate the template. The IaC MCP Server provides two validation tools that wrap open source checkers: cfn-lint for syntax validation and cfn-guard for policy-as-code compliance checks.

Prompt:

Validate iac-mcp-blog-app-stack.yaml for syntax errors and compliance violations.

The AI assistant runs two checks:

  1. Syntax validation (validate_cloudformation_template): Uses cfn-lint to catch structural errors, invalid property names, and schema violations.
  2. Compliance check (check_cloudformation_template_compliance): Uses cfn-guard to evaluate the template against security rules such as S3 bucket encryption, public access block settings, and log group retention.

If either check reports issues, ask the AI assistant to fix them. Continue iterating until both checks pass.

Note that the compliance check might flag violations related to S3 object lock, access logging, replication, and inline IAM policies. For a production workload, you would address each of these issues. In this walkthrough, the AI assistant resolves them to demonstrate the iterative validate-and-fix workflow. Your results might vary depending on the template the AI assistant generated in Step 1.

After the AI assistant resolves the violations, the S3 bucket resource gains access logging and object lock properties. The following snippet shows the typical shape of these additions (see iac-mcp-blog-app-stack-fixed.yaml in the companion repository for the complete hardened template):

  S3Bucket:
    Type: AWS::S3::Bucket
    Properties:
      # ... existing properties ...
      LoggingConfiguration:
        DestinationBucketName: !Ref S3LoggingBucket
        LogFilePrefix: access-logs/
      ObjectLockEnabled: true
      ObjectLockConfiguration:
        ObjectLockEnabled: Enabled
        Rule:
          DefaultRetention:
            Mode: GOVERNANCE
            Days: 30

Your template now passes both cfn-lint and cfn-guard checks. These security improvements improve your template’s security posture but are unrelated to the deployment failure you’ll encounter next. The failure in Step 3 is caused by missing permission on the service role, not by anything in the template itself.

Step 3: Deploy the stack

With validation complete, deploy the template. This deployment will fail — not because of a template error, but because the CloudFormation service role deployed in the prerequisites is missing iam:PassRole. This is the scenario you’ll diagnose in Step 4.

Now deploy the validated template using the service role you created in the prerequisites:

Prompt:

Deploy iac-mcp-blog-app-stack.yaml as a stack named “iac-mcp-blog-app-stack” in us-east-1 using the service role ARN from iac-mcp-blog-role-stack.

The AI assistant runs the AWS CLI deployment command for you. If your AI assistant doesn’t support running shell commands directly, you can deploy manually with the AWS CLI:

Manual CLI deployment

ROLE_ARN=$(aws cloudformation describe-stacks \
  --stack-name iac-mcp-blog-role-stack \
  --query "Stacks[0].Outputs[?OutputKey=='ServiceRoleArn'].OutputValue" \
  --output text)

aws cloudformation deploy \
  --template-file iac-mcp-blog-app-stack.yaml \
  --stack-name iac-mcp-blog-app-stack \
  --role-arn $ROLE_ARN \
  --capabilities CAPABILITY_NAMED_IAM

The deployment fails. The stack event shows an AccessDenied error on the IAM role resource, but doesn’t identify which permission on the CloudFormation service role is missing or why. At this point, we move from static analysis to runtime troubleshooting.

Step 4: Troubleshoot the failure

Ask the AI assistant to diagnose the failure:

⚠ Note: CloudTrail events typically take 5–15 minutes to appear. Wait at least 5 minutes after the deployment failure before running the troubleshoot tool for the most complete analysis.
Prompt:

Troubleshoot the failed deployment of iac-mcp-blog-app-stack in us-east-1.

The AI assistant calls troubleshoot_cloudformation_deployment, which:

  1. Retrieves the stack events and identifies the failed resources
  2. Correlates the failure timestamps with CloudTrail API calls
  3. Identifies AccessDenied errors and the missing permissions that caused them

The troubleshoot tool identifies that the CloudFormation service role is missing iam:PassRole — the permission required to assign the Lambda execution role to the function. If your template includes the cfn-guard hardening from Step 2 (access logging, object lock), the tool may also surface additional missing S3 permissions such as s3:PutBucketObjectLockConfiguration for the logging bucket.

Prompt:

Fix iac-mcp-blog-role-stack.yaml to add the missing permissions identified by the troubleshoot tool. Save it as iac-mcp-blog-role-stack-fixed.yaml.

The AI assistant adds the missing permissions to the service role template. Now ask the AI assistant to deploy the fix, delete the failed stack, and redeploy:

Prompt:

Deploy iac-mcp-blog-role-stack-fixed.yaml to update iac-mcp-blog-role-stack, then delete the failed iac-mcp-blog-app-stack and redeploy it with the same service role.

The AI assistant runs the necessary CLI commands: updating the role stack, deleting the failed application stack, and redeploying the application stack. The failed stack is in ROLLBACK_COMPLETE state, a terminal state that CloudFormation cannot update in place, so you must delete it before redeploying.

The stack deployment succeeded.

Cost considerations

For information about costs associated with the resources in this walkthrough, including S3 storage, Lambda invocations, CloudWatch Logs, and CloudFormation operations, see AWS Pricing. Confirm that your account usage falls within any applicable free tier limits. If you enabled S3 access logging or object lock through the validation-and-fix workflow in Step 2, the logging bucket stores a small amount of access log data that falls under S3 standard pricing. See AWS Pricing for current rates and confirm that your account is within the Free Tier limits before you deploy.

Cleaning up

To avoid ongoing charges, delete both stacks.

Option A: Clean up with your AI assistant

Ask your AI assistant to run the cleanup for you. The IaC MCP Server lets the AI assistant inspect stack outputs, empty buckets, and delete both stacks in the correct order:

Clean up the iac-mcp-blog-app-stack and iac-mcp-blog-role-stack stacks in us-east-1. Empty any S3 buckets they created (including access log buckets) before deleting the application stack, then delete the role stack.

Option B: Clean up manually

Delete the application stack first because it was deployed with the service role:

⚠ Warning: If your template included access logging, the logging bucket may contain objects. CloudFormation cannot delete a non-empty bucket. Empty it first:

aws s3 rm s3://<logging-bucket-name> --recursive

Then proceed with stack deletion.

aws cloudformation delete-stack --stack-name iac-mcp-blog-app-stack
aws cloudformation wait stack-delete-complete --stack-name iac-mcp-blog-app-stack

aws cloudformation delete-stack --stack-name iac-mcp-blog-role-stack
aws cloudformation wait stack-delete-complete --stack-name iac-mcp-blog-role-stack

If any S3 bucket was created with DeletionPolicy: Retain or still contains objects (for example, server access logs), CloudFormation leaves it in place. Empty and delete those buckets from the S3 console or with aws s3 rb s3://<bucket-name> --force.

Next steps

If you manage CloudFormation infrastructure and find yourself losing time to context-switching between docs, linters, consoles, and logs, here’s how to streamline your workflow starting today:

  1. Set up the IaC MCP Server — Install and configure the IaC MCP Server with an MCP-compatible AI assistant such as Kiro to bring documentation search, validation, and troubleshooting into a single conversational interface.
  2. Run the walkthrough end-to-end — Clone the companion repository and follow this post step by step to experience the full author-validate-deploy-troubleshoot loop in your own AWS account.
  3. Integrate into your team’s workflow — Replace manual context-switching by embedding the IaC MCP Server’s tools into your day-to-day CloudFormation development process, reducing iteration time from hours to minutes.
  4. Extend to AWS CDK — Apply the same conversational workflow to CDK-based infrastructure using the IaC MCP Server’s CDK capabilities described in the introductory blog post.
  5. Contribute and share feedback — Report issues or suggest enhancements on the AWS MCP GitHub repository to help shape future capabilities.

Conclusion

In this walkthrough, you used the IaC MCP Server to move through a complete CloudFormation development cycle without leaving your AI assistant. The documentation search tool retrieved up-to-date resource property references that the AI assistant used to generate a template. The validation tools caught syntax errors and compliance gaps before deployment. When the deployment failed due to missing permissions on the service role (an issue that static analysis cannot detect), you used the troubleshoot tool to correlate stack events with CloudTrail and pinpoint the root cause in seconds.

By combining static validation with runtime diagnostics, you shorten your develop-validate-fix cycle for CloudFormation. Instead of switching between browser tabs, CLI sessions, and the CloudTrail console, you stay in one interface — turning a multi-step troubleshooting session that previously meant switching between consoles, CLI sessions, and CloudTrail into a few prompts in a single conversation.

To get started, explore the companion GitHub repository for the complete sample code. Learn more about the IaC MCP Server in the introductory blog post and the AWS CloudFormation documentation. To set up Kiro, visit kiro.dev.


About the authors

Shuto Yukawa is an Associate Delivery Consultant at AWS Professional Services. He helps customers modernize their applications and adopt cloud-native practices on AWS.

G SS Harsha Vardhan is an Associate Delivery Consultant at AWS Professional Services. He guides customers to migrate and transform their workloads to AWS, driving modernization across people, process, and technology.

The Agent Development Lifecycle has arrived on Cloudflare

Post Syndicated from Brendan Irvine-Broque original https://blog.cloudflare.com/agent-development-lifecycle/

Engineering managers spent the past few decades figuring out ways for many programmers to work together on a shared codebase. This work dates all the way back to the “Systems Development Lifecycle” (RAND, 1975) – today commonly referred to as the “Software Development Lifecycle” (SDLC), which defines the following phases:

  • Plan
  • Design
  • Implement
  • Test
  • Deploy
  • Maintain
  • Retire

AI has made the step that was previously the slowest and most expensive — implementation — the fastest and cheapest. That, in turn, has had an impact downstream: overwhelming the people responsible for all the other steps in the SDLC. This ranges from open-source maintainers bombarded with thousands of pull requests and issues, to production engineers trying to save production from falling over as the rate of software delivery increases orders of magnitude.

We are all trying to save our systems, our customers, and ourselves from slop.

The answer — paradoxically — is to empower agents to do more. It’s only fair! You’d never let an engineer on your team write code, expect someone else to validate it, merge it, deploy it, hold the pager in production, and triage incoming bugs. But that’s what most companies are doing right now with agents. Models have improved remarkably, and agents are running over longer time horizons, able to take on much larger tasks. But they are not yet used evenly across the SDLC.

Cloudflare treats agents as our customers. They can buy domains, create temporary accounts and use the entire Cloudflare API. We know that agents need APIs and tools to be able to manage the full SDLC on behalf of our customers — not just the start of it.

And so today we’re introducing the start of a new set of tools that let agents step beyond just generating code and take on more of the SDLC. We’re sharing what we’ve built and learned trying to solve this for ourselves:

There’s something bigger here though. When we look at the SDLC, even with the best automation, its assumptions do not scale for the volume of code agents can write and the pace at which software teams must move to compete. We think it’s time to replace the SDLC with the ADLC — the Agent Development Lifecycle.

The SDLC is for software teams. The ADLC is for software factories.

Right now, everyone is talking about building “software factories” — agent-driven systems that take input and autonomously build, improve, deploy and manage software. Take an input, whether it’s a production error, a bug report from a customer, or an idea for a new feature, and delegate it entirely to an agent.

Even with agents, most software projects are constrained by human-in-the-loop steps. Humans prompting agents, telling them to keep going, instructing agents to apply feedback from a code review, constantly babysitting many agents and giving them instruction. On most software teams, the human still manages each step in the SDLC model — the only change is that they delegate tasks within each step to an agent.

And so the dream behind software factories is: what if you reimagined this approach and built a factory for the entire process of building software? How can we shift more human time towards the things that truly require human inspiration, taste, and judgement? It would leave us more time to design, to talk to customers, and to dream bigger.

A software factory has to manage the same steps in the SDLC, but it demands much more from the platform it is built on. Because when you hand over the keys and let the agent drive, every manual step that previously relied on a human must be adapted to be:

  • Programmatic — ”ClickOps” was bad practice for humans, but it’s a non-starter for agents. Every last operation needs APIs that agents can call, debug, and rely on.
  • Horizontally scalable — preview deployments were a nice-to-have when humans stared at the screen while building or manually took over a staging server to catch issues before production. For agents to drive, every agent must have its own preview that matches production.
  • Reproducible — what happens if there’s a bug that you can only reproduce when simulating 4G on an iPhone 15? Or from an IP in a certain country? Typical unit testing and integration testing tools aren’t going to help here.
  • Real-time, push based — relying on humans to look at the right dashboard has always been a bad way to know if things are working, but it completely breaks down with agents. You need an event that triggers an agent to do work.
  • Atomic — every change needs to be independently testable, releasable, observable, and reversible without affecting unrelated behavior.
  • Permissioned — you know you probably shouldn’t, but today you give a few trusted engineers the keys to SSH into prod in case things really go haywire. There’s no way you let an agent do that — but without the ability to escalate and get more permissions, how can it do its job?
  • Self-improving — people learn from experience. The first week ship or the first on-call rotation, humans are slow and need to shadow someone else, but then get better and faster. Agents, too, need ways to learn from experience.

We need something new if we are going to make software factories safe to use for real production software. Software factories face the same challenge that other autonomous systems like self-driving cars do — the challenge of going from working successfully 80% of the time, to some number of nines past 99%.

To give agents the keys to drive the SDLC, you can’t give them a car designed for humans

An autonomous vehicle is loaded with sensors and technology that a regular car doesn’t have. Lidar sensors, cameras, powerful compute to run inference, and connectivity to a central command system that can take over remotely if needed.

For an autonomous vehicle to be 80% as good as a human at driving, we probably don’t need all of this. Self-driving got to around 80% as good as humans 10 years ago. But that’s not the bar to clear — the bar is to be much better and safer than a human driver. That’s what we expect when we hand over the keys to a machine, in order to feel safe taking a nap driving down the 101 at 60 mph. And that’s why autonomous vehicles have technology that is purpose-built for self-driving — it’s what builds trust and handles the edge cases that cannot be designed for upfront.

The same is true of self-driving software. Ask yourself — why haven’t you yet just let your agent auto-approve and merge its own PRs to your production services? The higher the stakes of what you build, the longer your list of reasons almost surely is.

When you start to unpack not only all the things that can go catastrophically wrong in this process, but also that are necessary to building the right thing for customers, it is remarkably complex. It doesn’t fit into a linear set of steps in a GitHub Actions YAML file, and it goes way beyond running traditional automated tests. Even a small change to a dashboard can span roles, specializations and org structures, and subjective changes are the hardest to test and to delegate. Most of these things are probably not part of your CI/CD pipeline at all today. But they will need to be, if you want them to still happen, while giving full control to the agents running the software factory.

To let agents drive the whole process, we need a better way to orchestrate these dynamic series of steps. We think that is a Workflow, with the capability to spawn containers, agents and browsers. A Workflow that can set feature flags and enable them for a test user, investigate logs and traces, observe production metrics as a change gradually rolls out, and do everything else that is needed in order to ship safely.

A CI/CD pipeline is just a Workflow. But a Workflow can be so much more than a CI/CD pipeline.

Cloudflare Workflows let you chain together multiple steps, automatically retry failed tasks, and persist state for minutes, hours, or even weeks. They are designed to encode complex and dynamic business processes in a logical and well-understood program. This blog post breaks down why Workflows, in tandem with Artifacts, make defining and triggering CI/CD pipelines fundamentally simpler. For example:

Workflows go beyond a series of linear steps though. They can be defined dynamically, and they can spawn agents or other Workflows. This example shows a Workflow that reviews new data from the past day. The Workflow has full control over when and how the agent is prompted, and can pass along context between steps: 

Once you see this pattern, and are “Workflow-pilled” as Cloudflare is, you start to ask: what else could I have a Workflow handle for me? What other human-bottlenecked steps could I delegate to this combination of Workflow + Flue agents?

The full ADLC, on the Cloudflare stack

With Workflows able to orchestrate complex steps, and Artifacts as the storage layer for code, when you look at the SDLC stages, everything an agent needs to own the whole process of building, shipping, and maintaining software is on Cloudflare:

Primitives to build your software factory

Right now, the people on the bleeding edge are building the software factories of the future. Eventually software factories will become, just like agents and AI, the normal way people build software. But for most people and most organizations, we’re not there yet.

We want to change that.

In order to do so, the questions we’ve asked ourselves are: how can we make things simple and accessible so that everyone on the Internet can benefit from a paradigm shift like this? And what are the base layer primitives that we can open up to everyone, from the smallest startup to the largest platforms in the world?

In this case, we think the primitives are here. There’s more to do to connect them, to keep building our own software factory and learn from it, but right now, today, we’re ready for you to build your machine that builds the machine, on Cloudflare. Get started with @cloudflare/ci, build an agent, and see how much of the SDLC you can make autonomous.

How Company 3 Streamlines Studio Image Management with EC2 Image Builder and AWS CDK

Post Syndicated from Natalie White original https://aws.amazon.com/blogs/devops/how-company-3-streamlines-studio-image-management-with-ec2-image-builder-and-aws-cdk/

Guest post in collaboration with Company 3 Director of New Technology, Phil Wortas, and Senior New Technology Engineer, Matthew Galloway

Introduction

Company 3 provides specialized services for the entertainment industry, including post-production services, visual effects, and color grading for feature films, commercials, and television content. Their teams collaborate globally to Increase workflow efficiency and expand their roster of diverse movie-making talent.

Company 3’s New Technology team uses Amazon EC2 Image Builder to vend Amazon Machine Images (AMIs) and container images for compute environments where artists create and render content. Image Builder is a fully managed AWS service that helps you automate the creation, management, and deployment of customized, secure, and up-to-date server images. Company 3 also uses the AWS Cloud Development Kit (CDK) to scale the creation of consistent Image Builder components and recipes.

At scale, the respective concepts of versioning between Image Builder resources and CDK infrastructure as code made it challenging to reuse prior components and recipes, and update existing references with new version numbers over time. This challenge led to creative workarounds, collaborative problem-solving with AWS, and ultimately, product improvements that benefit the entire AWS community.

This blog follows their journey from manual version management, through creative workarounds, to native EC2 Image Builder features that solved the problem for good. Along the way, we’ll show how auto-versioning and CDK L2 constructs can simplify your own image pipelines.

Process flow diagram of Artists, Support Engineers, and New Technology Platform Engineers provisioning new studio environments. (1) Artists request new environments. (2) Automation determines whether a matching environment configuration (EC2 AMI) exists. If it does, (3) the new environment is provisioned for the Artist to securely access. If it does not, (4) a Support Engineer creates or update an (5) CDK definition of an EC2 Image Builder Pipeline to provision the correct environment. The CDK (6) generates a CloudFormation template and assets that are used to (7) create the Pipeline. This Pipeline (8) generates a new EC2 AMI, from which the rendering instance can be (9) provisioned and (10) provided for the Artist to securely access.

Figure 1: Personas and process flow

The Challenge: When Infrastructure-as-Code Gets Complicated

While Image Builder has historically supported semantic versioning for Components and Recipes, there was no mechanism to automatically detect version changes or update existing references to the latest version of a component using the CDK. This is because Image Builder only supported Layer 1 (L1) CDK constructs. Layer 1 constructs map directly to CloudFormation resources and their corresponding service APIs, but do not provide features that create a layer of abstraction above those foundational create / update / delete operations.

Version changes to Components and Recipes are a frequent occurrence because these resources are immutable; every change to them requires a new version. Version numbers are a part of these resource’s Amazon Resource Name (ARN), so changes must be propagated throughout the associated CDK code to correctly reference the latest version of each resource.

Figure 2 shows an architecture diagram of an EC2 Image Builder Pipeline, which consists of Infrastructure configuration, Components, Recipes, and distribution settings. Components and Recipes each have their own separate version numbers and are immutable. This Pipeline generates EC2 AMIs, which are tied to the recipe version used to generate them, and are used to provision EC2 rendering instances.

Figure 2: EC2 Image Builder Anatomy and Version Propagation

Figure 1, Step 5 represents a Platform Engineer having to update an existing Component. Figure 2 shows the required changes broken out by each of the comprising Image Builder resources:

  1. Update the Component configuration
  2. Increment the Component version
  3. Update the Recipe with the new Component version ARN
  4. Increment the Recipe version
  5. Update the Recipe version ARN in the Pipeline.

Manual version propagation across dozens of components via this multi-step process was error prone, wasn’t scalable, and created a risk of deployment failures and version churn due to version mismatches.

The team needed to prevent unnecessary update requests to Image Builder when components didn’t change but the recipes they were associated with did, orchestrate version propagations when the versions did need to change, and track component versions as they deployed updates across their infrastructure.

Short-term Workaround: Using Hashes to Identify Changes

Faced with these limitations, the customer’s engineering team got creative. Their first approach involved appending MD5 hashes to component names. This allowed them to track changes and force CDK updates and version increments when content changed, while preventing unnecessary update calls when the content of the component didn’t change but the rest of the resources in the CDK Stack did.

However, this approach had drawbacks. Component names became unwieldy and difficult to maintain. More importantly, the hash-based naming convention didn’t align with semantic versioning best practices that the rest of their infrastructure followed. The team knew they needed a better solution long-term.

Long-term Automation: Collaboration with AWS

Working with their AWS Solutions Architect and EC2 Image Builder Developer Support, Company 3 developed a more elegant solution using CDK Custom Resources. This approach eliminated hash-based naming and automated the propagation of version updates, but it came with technical debt.

The version increments themselves were still manual, and the solution required custom resources to create and maintain the suite of resources being deployed. The mesh of custom resources required specialized knowledge to maintain, which made it difficult to onboard new team members, and distracted engineers from focus on core business value of delivering the right studio environments to artists.

Managed Abstraction: AWS Launches Product Improvements

EC2 Image Builder auto-versioning

In November 2025, EC2 Image Builder introduced native auto-versioning capabilities that transformed how teams manage Component versions.

Components with the same name and semantic version now auto-increment build versions (eliminating steps 2-4 from Figure 2 when developers use ‘x’ as a wildcard placeholder (e.g., 1.2.x). Additionally, Pipelines can resolve to the highest available version of Components and Recipes, which ensures they are using the latest compatible versions without manual updates, eliminating step 5.

These enhancements eliminated the version propagation burden entirely, allowing Company 3 developers to focus only on the substantive changes to Components requested by Artists and Support Engineers.

CDK Layer 2 Constructs

The second major improvement came with comprehensive Layer 2 (L2) constructs for EC2 Image Builder (RFC 0789). L2 Constructs provide a layer of abstraction that default to best practice configuration, automatic least-privilege IAM Role and Policy provisioning, and convenience methods that make it easier to create and link to other AWS resources. These constructs transformed the developer experience and alleviated the need for custom resources. The EC2 Image Builder L2 Construct is currently in alpha stabilization phase, and sourcing customer feedback and adoption before migrating to the core CDK library per the CDK contribution process.

Before the L2 construct release, orchestrating an Image Builder Pipeline took over 50 lines of code, and required manual least-privilege IAM role creation, instance profile setup, and Pipeline configuration across 6 separate CloudFormation resources.

// Using L1 constructs
const instanceProfileRole = new iam.Role(stack, 'EC2InstanceProfileForImageBuilderRole', {
  assumedBy: iam.ServicePrincipal.fromStaticServicePrincipleName('ec2.amazonaws.com'),
  managedPolicies: [
    iam.ManagedPolicy.fromAwsManagedPolicyName('AmazonSSMManagedInstanceCore'),
    iam.ManagedPolicy.fromAwsManagedPolicyName('EC2InstanceProfileForImageBuilder'),
  ],
});

const instanceProfile = new iam.InstanceProfile(stack, 'EC2InstanceProfileForImageBuilder', {
  role: instanceProfileRole,
});

const bucket = new s3.Bucket(stack, 'ImageBuilderLoggingBucket', {
 bucketName: `ec2imagebuilder-logs-${stack.region}-${stack.account}`,
  enforceSSL: true,
});

const l1InfrastructureConfiguration = new imagebuilder.CfnInfrastructureConfiguration(stack, 'L1InfrastructureConfiguration', {
  name: 'l1-infrastructure-configuration',
  instanceProfileName: instanceProfile.instanceProfileName,
  instanceMetadataOptions: { httpTokens: 'required' },
  logging: {
    s3Bucket: bucket.bucketName,
    s3KeyPrefix: 'imagebuilder-logging',
  },
});
const l1ImageRecipe = new imagebuilder.CfnImageRecipe(stack, 'L1ImageRecipe', {
  name: 'l1-image-recipe',
  version: '1.0.0',
  parentImage: `arn:${stack.partition}:imagebuilder:${stack.region}:aws:image/amazon-linux-2023-x86/x.x.x`,
  components: [
    {
      componentArn: `arn:${stack.partition}:imagebuilder:${stack.region}:aws:component/update-linux/x.x.x`,
    },
  ],
});

const l1ImagePipeline = new imagebuilder.CfnImagePipeline(stack, 'L1ImagePipeline', {
  name: 'l1-image-pipeline',
  imageRecipeArn: l1ImageRecipe.attrArn,
  infrastructureConfigurationArn: l1InfrastructureConfiguration.attrArn,
});

Using the ImagePipeline L2 construct allows the developer to provision a Pipeline in fewer than 10 lines of code while leveraging best practice configuration the construct sets by default.

// Equivalent, using L2 constructs
const l2ImagePipeline = new imagebuilder.ImagePipeline(stack, 'L2ImagePipeline', {
  recipe: new imagebuilder.ImageRecipe(stack, 'L2ImageRecipe', {
    baseImage: imagebuilder.AwsManagedImage.amazonLinux2023(stack, 'AL2023'),
    components: [
      {
        component: imagebuilder.AwsManagedComponent.updateOS(stack, 'UpdateOS', {
          platform: imagebuilder.Platform.Linux,
        }),
      },
    ],
  }),
});

The Impact: From Workarounds to Best Practices

For Company 3, these improvements meant they could retire their custom constructs entirely. The L2 constructs provided everything their custom solution did, plus additional capabilities.

The EC2 Image Builder service manages the complexity of version updates by default, and they gained enhanced security through AWS-managed secure defaults like IMDSv2 requirements and least-privileged IAM roles.

Perhaps most importantly, new team members can understand the infrastructure code in minutes rather than hours, dramatically accelerating onboarding.

Conclusion

The impact extends far beyond one customer. Every AWS user working with EC2 Image Builder and CDK now benefits from simplified workflows, automatic version management, and security best practices by default. What started as one team’s challenge became a catalyst for improvements that make everyone’s work easier and more secure. The evolution of EC2 Image Builder’s CDK support demonstrates AWS’s commitment to listening to customers and continuously improving the developer experience.

For teams currently managing EC2 Image Builder Pipelines manually or with L1 CDK constructs or with custom solutions, the path forward offers significant benefits. Explore how you can use EC2 Image Builder, its new auto-versioning capabilities, and its CDK L2 Constructs to automate your complex AMI Pipeline provisioning architecture via these resources:

EC2 Image Builder Documentation

EC2 Image Builder Auto-versioning Documentation

CDK L2 Constructs for EC2 Image Builder (currently in alpha stabilization)

EC2 Image Builder CDK Sample GitHub Repository

Authors

Rochelle Lakey

Rochelle Lakey is a Senior Solutions Architect specializing in Media and Entertainment at AWS helping customers architect and optimize their cloud infrastructure. She brings 28 years of managed services experience bridging traditional data centers and modern cloud computing. Rochelle is passionate about guiding organizations through their digital transformation journeys.

Phil Wortas

Phil Wortas is Director of New Technology at Company 3, where his team serves as the cloud infrastructure and platform engineering backbone for a global post-production and VFX organization. Together they focus on reducing manual toil through automation and IaC, so the creative teams they support can stay focused on the work that matters.

Matthew Galloway

Matthew Galloway is a Senior New Technology Engineer at Company 3, working within the cloud infrastructure team. He specializes in AWS deployment automation and developing tools that streamline and enhance artist workflows across the organization. Matthew’s work is driven by a commitment to reducing friction for creative teams, ensuring they have the reliable, efficient infrastructure that they need.

Tarun Belani

Tarun Belani is a Senior Software Development Engineer on the EC2 Image Builder team at Amazon Web Services, where he works on the service’s APIs and backend systems. He designed and built the AWS CDK L2 constructs for EC2 Image Builder.

Natalie White

Natalie White is a Principal Solutions Architect at Amazon Web Services. While her primary customers are in the Healthcare and Life Sciences industry, she leverages her prior Software Development experience as a specialist in AWS CDK and Infrastructure as Code automation, AI-DLC, and GenAI for Developer Productivity across all industries.

Add security context to operational investigations with AWS DevOps Agent and Wiz

Post Syndicated from Yuriy Prykhodko original https://aws.amazon.com/blogs/devops/add-security-context-to-operational-investigations-with-aws-devops-agent-and-wiz/

This post was co-authored by Ayelet Harcz (Product Manager), Hen Perez (CTO Architect), and Shani Gafni (Product Manager) at Wiz.

When an on-call engineer receives an alert at 2 AM, a CPU spike, a latency anomaly, or an unexpected API error, the first question is whether this is an operational issue or a security incident. A CPU spike could be a scaling problem or a cryptominer. A latency anomaly could be a bad deployment or data exfiltration. Without security context in the investigation loop, engineers lack the information to distinguish between the two, delaying resolution and increasing risk.

AWS DevOps Agent is a frontier agent that autonomously investigates incidents and identifies operational improvements across AWS, multicloud, and on-premises environments. It reduces mean time to resolution (MTTR) by performing the triage and investigation work that would otherwise take an on-call engineer hours of manual effort. With the Wiz integration, AWS DevOps Agent queries Wiz’s security graph during investigations through the Model Context Protocol (MCP), surfacing vulnerability data, security findings, and exposure analysis alongside operational telemetry so engineers can quickly determine whether an alert is a performance issue or a security incident.

In this post, we walk through how the integration works, demonstrate a real-world incident investigation where AWS DevOps Agent uses Wiz MCP to surface a critical vulnerability behind an API latency spike, and show how to configure the integration in your environment. If you already use Wiz to secure your AWS environment, this integration puts your existing security data to work during incident investigations.

AWS DevOps Agent

AWS DevOps Agent investigates incidents and identifies operational improvements as an experienced DevOps engineer would: by learning your resources and their relationships, working with your observability tools, runbooks, code repositories, and CI/CD pipelines, and correlating telemetry, code, and deployment data across all of them. For a deeper look at how it works, see How AWS DevOps Agent uses multi-agent reasoning to find root causes.

AWS DevOps Agent is extensible through MCP, which allows the agent to call external tools during its investigation without requiring custom development. This is the mechanism that makes the Wiz integration possible. When the agent identifies a resource under investigation, it queries Wiz MCP for security findings associated with that resource and incorporates the results into its analysis and recommendations.

Wiz MCP

Wiz is designed to secure cloud and AI applications through a unified, graph-powered platform. The Wiz Security Graph connects infrastructure, identities, data, AI components, and runtime activity into a single contextual view. This approach identifies toxic combinations across layers – where exposures, permissions, data access, AI vulnerabilities, and runtime behaviors intersect in ways attackers can realistically exploit.

The Wiz MCP Server acts as a standardized gateway that allows AWS DevOps Agent to query this security graph during investigations. Wiz knows whether your Amazon Elastic Compute Cloud (Amazon EC2) instance has an exploitable Common Vulnerabilities and Exposures (CVE), whether it is publicly exposed, and whether endpoint protection is in place. AWS DevOps Agent, looking at the same instance, knows that CPU spiked, and a deployment happened 20 minutes ago. Separately, each tool tells a partial story. Together, they give the engineer the complete picture needed to act.

Better together: how combined context changes triage

The value of this integration is easiest to understand through three scenarios. Each starts with the same operational signal: a CPU spike on an EC2 instance.

Figure 1 – AWS DevOps Agent sees operational telemetry, Wiz sees security posture. The combination changes the triage decision.

Figure 1 – AWS DevOps Agent sees operational telemetry, Wiz sees security posture. The combination changes the triage decision.

Scenario A: No security findings. A CPU spike fires on an instance. AWS DevOps Agent queries Wiz and confirms the instance is fully monitored, has no known vulnerabilities, and shows zero active threat detections. This is an operational issue. The engineer scales, investigates the deployment, tests, and moves on.

Scenario B: Security issue detected. The same CPU spike fires, the same Amazon CloudWatch alarm triggers, and the same engineer wakes up. But when AWS DevOps Agent queries Wiz, it finds a validated remote code execution vulnerability on that instance, confirmed exploitable, with the resource exposed to the internet. The operational symptoms are identical to Scenario A. The correct response is the opposite: isolate immediately, engage your security team, treat this as a potential compromise.

Scenario C: Wiz coverage gap. The resource isn’t in Wiz at all. AWS DevOps Agent includes this as a finding in the investigation report, noting that no security context was available for the resource. Your team can then address the coverage gap by onboarding the resource into Wiz.

Without the Wiz integration, all three scenarios look the same in your dashboard. With it, AWS DevOps Agent routes each to the correct response path before a human needs to context-switch between tools.

How the integration works: the MCP bridge

The integration uses MCP, the same protocol AWS DevOps Agent uses for many of its external tool connections. When the agent identifies affected resources during an investigation, it calls Wiz’s remote MCP server as part of its evidence collection – no separate step, no manual trigger. The security query happens alongside the operational investigation, not after it. During the MCP call, AWS DevOps Agent sends resource identifiers to Wiz’s MCP endpoint and receives security findings in response. No operational telemetry or broader investigation context is shared with Wiz.

Figure 2 – The investigation flow: operational alert triggers AWS DevOps Agent, which queries Wiz via MCP before reaching a triage decision.

During the MCP call, AWS DevOps Agent queries Wiz tools to build a complete risk picture of the affected resource, here are a few examples:

Wiz MCP Tool What it tells the agent
list_cloud_resources Whether Wiz monitors this resource at all (coverage check)
list_findings All finding types in one call: vulnerabilities, misconfigurations, secrets, data, and host config
list_vulnerability_findings Deep CVE detail – severity, fix version, and exploitability (CISA KEV / known exploit)
list_issues Prioritized risk issues, including toxic combinations (internet-facing + no Endpoint Detection and Response (EDR) + exploitable CVE)
list_threats / list_malware_findings Active threats and malware: cryptomining, data exfiltration, backdoors
list_detections Recent threat detection signals and anomalous activity
get_green_agent_analysis AI-generated remediation steps for the issues found

The agent runs these queries together through a single security-auditing skill that loads automatically when it connects to Wiz’s MCP server with the DevOps toolset, so the full security picture comes back in seconds. If the Wiz MCP server is unreachable, times out mid-query, or returns an authentication error, the agent continues its investigation with the operational data it has and flags the missing security context in the investigation findings (Scenario C). You can review exactly which MCP tools were called and what data was returned in the AWS DevOps Agent investigation log for full auditability.

Based on what comes back, the agent classifies the situation: no security findings (operational issue, proceed normally), compromised or at-risk (active threats, exploitable vulnerabilities, or toxic combinations – apply relevant security runbooks to isolate the resource or escalate to security, with Wiz Green Agent remediation steps attached), or unmonitored by Wiz (flag and close the coverage gap). The classification feeds directly into the investigation findings your team receives.

The following demonstration shows AWS DevOps Agent investigating a reported CPU spike. The agent queries Wiz MCP and identifies a critical, internet-exposed Remote Code Execution (RCE) under active exploitation – turning an ambiguous alert into a confirmed security incident.

Video 1 – AWS DevOps Agent investigates a CPU spike and uses Wiz MCP security context to identify a critical RCE exploited through a public endpoint

Getting started

Prerequisites

To use AWS DevOps Agent with Wiz MCP, you need:

  1. An active AWS DevOps Agent configuration with at least one Agent Space
  2. A Wiz tenant with a remote MCP server endpoint (Streamable HTTP transport)
  3. Authentication credentials for the Wiz MCP server. AWS DevOps Agent supports multiple MCP auth methods; for Wiz, use a Wiz service account (Client ID and Secret) or OAuth. Choose the method that matches your Wiz MCP server configuration. For setup details, see Connect remote Wiz MCP server in the Wiz documentation (requires Wiz login)

Enabling the integration

Step 1: Register the Wiz MCP server at account level

  1. Sign in to the AWS Management Console and navigate to the AWS DevOps Agent console.
  2. Go to the Capability Providers page from the side navigation.
  3. Find MCP Server in the Available providers section and choose Register.
  4. Enter the Wiz MCP server details:
    • Name: e.g., “Wiz Security”
    • Endpoint URL: https://mcp.app.wiz.io/?toolset=devops
    • Description: e.g., “Wiz security context for incident triage”
  5. Choose Next.
  6. Select the authentication method that matches your Wiz MCP server configuration.
  7. Review your configuration and choose Submit. AWS DevOps Agent validates the connection to the Wiz MCP server. Upon successful validation, the server is registered at the account level.

Step 2: Allowlist Wiz tools in your Agent Space

  1. In the AWS DevOps Agent console, select your Agent Space.
  2. Go to the Capabilities tab.
  3. In the MCP Servers section, choose Add.
  4. Select the registered Wiz MCP server.
  5. Select all the Wiz MCP tools.
  6. Choose Add.

Step 3: Choose how the Wiz security audit runs

Pick one of three options:

  1. Use the Wiz skill tool (recommended). With the Wiz MCP tools allowlisted, AWS DevOps Agent automatically runs the latest devops_resource_auditing_skill workflow from Wiz during investigations. You always get the most up-to-date version, maintained by Wiz.
  2. Import the ready-made skill. Import the wiz-security-context skill from the AWS DevOps Agent skills repo directly into your Agent Space. It is a lightweight skill that calls the Wiz workflow for you, so you get a one-step setup that stays current with Wiz.
  3. Create your own custom skill. Use AWS DevOps Agent’s Create skill with Chat to build a custom skill based on the devops_resource_auditing_skill workflow and tailor it to your environment. This lets you review and tailor the workflow to your environment.

For detailed MCP configuration guidance, refer to the AWS DevOps Agent documentation on connecting remote MCP servers.

The power of co-build: extending context through MCP

This integration started from a recurring customer question: how do I know if what I’m seeing is an operational problem or an active attack? We worked with Wiz to close this gap. AWS DevOps Agent provides operational investigation and reasoning; Wiz provides cloud security intelligence. MCP provided the integration path without either side needing to reimplement what the other already does well.

Because AWS DevOps Agent supports connecting remote MCP servers as a first-class extension mechanism, co-building new integrations with AWS Partners follows a repeatable pattern. Each integration adds a new dimension of context to the agent’s reasoning, and you benefit without writing custom code or middleware on your side. For example, connecting a change management MCP server would let the agent correlate deployment approvals with incident timing, adding change context alongside security context.

For you, this means the richer the toolset you run in your environment, the more context the agent brings to each investigation. Your existing investments get amplified rather than duplicated, and you benefit each time you connect a new partner MCP server to your Agent Space.

Conclusion

Operational incidents and security incidents often start with the same symptoms. The difference between the right response to each is context that lives in a different tool than the one that fired the alert. The AWS DevOps Agent and Wiz integration brings that context into the investigation loop automatically through MCP.

To get started, visit the AWS DevOps Agent console and follow the getting started guide. To learn more about Wiz’s MCP server, see Introducing the MCP Server for Wiz.

Wiz is an AWS Partner and AWS Marketplace Seller providing cloud security across the full development lifecycle. If you’re not already using Wiz, you can get started through the AWS Marketplace.

About the Authors

Yuriy Prykhodko

Yuriy Prykhodko is a Principal Technical Account Manager at AWS, based in Luxembourg. He partners with customers to architect highly reliable, cost-effective systems and drive operational excellence across their cloud workloads, with a focus on applying AI to streamline cloud operations. Yuriy is also an active contributor to the Cloud Operations Technical Field Community at AWS, where he leads several initiatives at the intersection of AI and cloud operations. Outside of work, he enjoys playing basketball and exploring new destinations around the world.

Ziv Shenhav

Ziv is a Principal Customer Solutions Manager at AWS. With nearly a decade at AWS, he helps ISV customers across EMEA accelerate modernization and transition into the agentic AI era. Outside of work, Ziv enjoys nature photography.

Yossi Lagstein

Yossi Lagstein is a Senior Solutions Architect at Amazon Web Services. Yossi has over 30 years of experience as specialist and manager in developing infrastructure components for a variety of projects and products. Yossi supports AWS customers to evolve, design and build well architected solutions. Outside of works, Yossi enjoys running , swimming and hiking.

Ayelet Harcz

Ayelet is a Product Manager at Wiz focused on the frontier of agentic AI engineering. She leads product initiatives and scaling coverage around Mika-Wiz’s AI assistant-and its expanding MCP ecosystem to deliver intelligent cybersecurity capabilities. She holds a degree in Computer Science and Cognitive Science, and outside of work, she enjoys practicing yoga

Hen Perez

Hen is a CTO Architect at Wiz, specializing in cloud security and agentic AI. He architected and co-built the patented Wiz MCP Server, enabling organizations to build AI-powered security agents on top of Wiz, and works across the Wiz Integration Network (WIN) and its MCP ecosystem. With over 19 years of experience spanning embedded systems, observability, and cybersecurity, he focuses on unlocking secure agentic workflows. In his free time, he enjoys playing the piano, experimenting with AI and synthesizers, and hacking life with his daughter.

Shani Gafni

Shani is Product Manager at Wiz, specializing in agentic AI engineering. Her work centers on Wiz’s core AI assistant, Mika along with Wiz Green agent, MCPs and related tools, delivering innovative cybersecurity solutions. In her free time, she enjoys books, music, nature, and photography.

Accelerating AWS Network Firewall troubleshooting with AWS DevOps Agent

Post Syndicated from Salman Ahmed original https://aws.amazon.com/blogs/security/accelerating-aws-network-firewall-troubleshooting-with-aws-devops-agent/

When an administrator introduces a rule change in AWS Network Firewall and network connectivity is disrupted, pinpointing the cause requires inspecting multiple points in the traffic path. The firewall gives you stateless and stateful rule engines, domain rules, and routing to the firewall endpoint inside your Amazon Virtual Private Cloud (Amazon VPC). A network drop looks the same from the workload no matter where it started. Isolating the cause means correlating the alert and flow logs with the firewall configuration, route tables, and recent API calls in AWS CloudTrail that might have changed them. That manual correlation is exactly where AWS DevOps Agent helps, accelerating root cause analysis so you can restore connectivity in minutes instead of hours.

AWS DevOps Agent does that correlation for you. As your always-available operations teammate, it resolves and proactively prevents operational issues across AWS, multicloud, and on-premises environments. When an Amazon CloudWatch alarm triggers, it reaches the agent through a webhook. The agent then reads the firewall configuration and logs through AWS APIs, ties the drop to recent API activity, and returns a root cause with a mitigation plan you review before you apply it.

This post connects CloudWatch monitoring to DevOps Agent. It walks through three Network Firewall failures from end to end. The first is a domain deny list blocking a legitimate endpoint. The second is a stateless rule priority misconfiguration. The third is an asymmetric cross Availability Zone (AZ) routing drop. Each maps to a different layer, so each leads down a different investigation path. An AWS Cloud Development Kit (AWS CDK) app deploys the whole environment in your own account so you can reproduce each failure and follow along.

The sample workload

As part of this blog post, we provide a CDK stack that deploys both the AWS DevOps Agent Space and a sample workload used to walk through three separate troubleshooting scenarios. A single t3.micro instance in a protected subnet checks its connectivity to a test endpoint on a continuous loop and publishes results to CloudWatch. Traffic takes the internet egress path through Network Firewall, the NAT gateway, and the internet gateway, so the firewall can intercept or drop it. After completing the walkthrough, you can apply the same troubleshooting techniques with DevOps Agent against your own Network Firewall deployments.

The test endpoint runs in a separate VPC deployed by the same CDK app. It serves HTTPS on port 443 and TCP on port 9142, giving each scenario a different protocol layer to exercise: Scenario 1 targets a TLS connection on 443 (matched by Server Name Indication), Scenario 2 targets a TCP connection on 9142, and Scenario 3 exercises the whole egress path.

A live status page shows one card per scenario plus the network topology. The whole stack deploys from a single CDK app across two Availability Zones, each with a firewall endpoint and NAT gateway, which is what makes Scenario 3 possible.

As shown in the following figure, the egress data path runs from the workload through Network Firewall and the NAT and internet gateways to the test endpoint. The alarm pipeline runs from CloudWatch through Amazon Simple Notification Service (Amazon SNS) and the webhook AWS Lambda function to DevOps Agent.

Figure 1: The sample workload

Figure 1: The sample workload

To use this with your own workload, you need a CloudWatch alarm that detects the connectivity problem and the webhook pipeline (SNS topic and Lambda function) that delivers it to DevOps Agent. The agent reads your firewall configuration, logs, and CloudTrail through AWS APIs, so no additional instrumentation is needed on the firewall side.

Prerequisites

To follow along with this post, you need:

Deploy the sample workload

Clone the project and deploy it into us-east-1 with one command (set awsRegion to use another AWS Region).

git clone https://github.com/aws-samples/sample-accelerating-aws-network-firewall-troubleshooting-with-aws-devops-agent.git
cd sample-accelerating-aws-network-firewall-troubleshooting-with-aws-devops-agent
bash scripts/deploy.sh

The script checks prerequisites, installs dependencies, compiles and tests, and bootstraps the CDK if needed. It then deploys all the stacks from a clean baseline and prints the outputs, including the status-page URL and sign-in details.

  1. Open the status-page link (an https://<random-id>.cloudfront.net address).
  2. Sign in using the username and password provided from the CDK output and confirm all three cards show the green Healthy status.
  3. Keep the page open while you run the scenarios.

Connect AWS DevOps Agent

To connect AWS DevOps Agent to the alarm pipeline

  1. In the AWS DevOps Agent console, open the nf-devops-agent-space Agent Space created by the CDK deployment.
  2. Configure the DevOps Agent webhook and download the CSV file with the webhook URL and signing secret.
  3. On the status page, choose Configure webhook, paste the URL and signing secret, and save. The page writes them to the nf-devops-agent-webhook-credentials AWS Secrets Manager secret, so there is no AWS CLI or console step. Until you set it, the bridge Lambda function sees a placeholder and skips delivery.
  4. Verify the path before you run a scenario. In the Lambda console, open nf-devops-agent-webhook and use the Test tab with this event.
    {
      "Records": [
        {
          "Sns": {
            "Message": "{\"AlarmName\":\"TEST-webhook-verification\",\"AlarmDescription\":\"[TEST] Webhook integration test - not a real alarm.\",\"NewStateValue\":\"ALARM\",\"NewStateReason\":\"[TEST] Manual webhook connectivity test. Safe to ignore.\",\"Region\":\"us-east-1\"}"
          }
        }
      ]
    }

  5. A 200 response confirms the path, and a test investigation appears in the DevOps Agent Operator Web App view.

How the alarm pipeline works

Every scenario reaches DevOps Agent the same way. A CloudWatch alarm moves to ALARM and notifies the SNS topic. Amazon SNS invokes a Lambda function. The function reads the webhook URL and signing secret from Secrets Manager, signs an alarm payload, and POSTs it to the DevOps Agent webhook (as shown in Figure 1). Amazon SNS also provides delivery retries, fan-out to other subscribers, and cross-account publishing.

  • Prebuilt Network Firewall metric (Scenario 1) Alarm-1 watches the DroppedPackets metric, summed across the stateful streams, and triggers when drops rise above a baseline threshold. This requires no workload or custom metric and works on an already-deployed firewall. However, it only tells you that the firewall is dropping packets, not which rule is responsible.
  • Application health metric (Scenarios 2 and 3) Alarm-2 and Alarm-3 watch a custom metric from a connectivity check. Use this for an alarm tied to user-facing impact or to tell one traffic path from another, which requires running a component that emits the metric.
Alarm Source Triggers when
Alarm-1 Native AWS/NetworkFirewall DroppedPackets The firewall’s dropped-packet count rises above the baseline
Alarm-2 Custom application health metric The port 9142 (TCP) connectivity check to the test endpoint is being dropped
Alarm-3 Custom application health metric The cross Availability Zone connectivity check is being dropped

Run the scenarios

Work through each of the scenarios one at a time, following the same cycle. Interrupt network connectivity, watch the alarm trigger, let DevOps Agent investigate, apply the recommended fix, and confirm recovery before moving on.

The status-page cards follow the live CloudWatch alarm state. A card shows a green dot and the word Healthy when its alarm is clear, and a red dot and the word DROPPED when its alarm triggers. In the DROPPED state the card also adds a Condition: line describing what’s being dropped, which isn’t shown when the card is healthy. Network Firewall applies changes to new flows, so a change shows within a minute or two. Recovery comes from the mitigation DevOps Agent recommends, which you review and apply.

Scenario 1. Domain deny list blocking a legitimate endpoint

At baseline, the rg-domain Suricata domain rule group denies only an unused placeholder, so the test endpoint stays reachable. The rule group inspects the TLS Server Name Indication (SNI) on each outbound connection and drops any that matches a denied domain. The exact rule syntax and console steps follow.

To add the domain deny rule

  1. Go to the Amazon VPC console.
  2. In the navigation pane, under Network Firewall, choose Network Firewall rule groups.
  3. Choose the rg-domain rule group to open its details page.
  4. In the Rules section, choose Edit.
  5. The rules box already contains two baseline placeholder rules (they match blocked.placeholder.invalid, so nothing real is denied). Leave those in place. Find the <app-endpoint-dns> value for Scenario 1 in the deployment script output (a Nework Load Balancer (NLB) DNS name such as NfTest-AppNl-a1b2C3dEf4G5-1234abcd5678efgh.elb.us-east-1.amazonaws.com). On a new line below the existing rules, add a drop rule that matches that DNS name on the TLS SNI, then choose Save.
    drop tls $HOME_NET any -> $EXTERNAL_NET any (ssl_state:client_hello; tls.sni; content:"<app-endpoint-dns>"; startswith; nocase; endswith; msg:"S1 domain denylist"; flow:to_server, established; sid:2000002; rev:1;)

  6. After saving, the rules box holds all three lines. The two placeholders remain, plus the new drop rule for the endpoint DNS name (note the distinct sid 2000002).
Figure 2: Scenario 1 – Firewall rule change blocking the connection

Figure 2: Scenario 1 – Firewall rule change blocking the connection

What happens. The workload’s HTTPS check to the test endpoint times out, the “AWS/NetworkFirewall DroppedPackets metric climbs above baseline, and Alarm-1 moves to ALARM. The Scenario 1 card reads DROPPED (with the condition Firewall dropping the monitored domain on its allow/deny rules), while the Scenario 2 and Scenario 3 cards stay Healthy (Figure 3). On the topology, the alarm pipeline from CloudWatch through Amazon SNS and Lambda to DevOps Agent and the workload-to-firewall inspect lines both turn amber, which the legend defines as collateral / alarm active, because the packets are now dropped at the firewall. To demonstrate the resulting failure, the HTTPS · SNI line from the internet gateway to the test endpoint is shown in red, which the legend defines as dropped (root cause).

Figure 3: Scenario 1 active – Traffic blocked at the firewall

Figure 3: Scenario 1 active – Traffic blocked at the firewall

Let DevOps Agent investigate. The agent runs several lines of investigation in parallel and correlates them:

  1. Reads the DroppedPackets metric and correlates the spike with a simultaneous drop in passed packets, confirming the firewall is actively blocking traffic.
  2. Reads the ALERT log and finds the workload’s TLS connections to the test endpoint blocked by the S1 domain denylist rule.
  3. Compares the current state against a baseline window, where the same endpoint was reachable with no alerts, which shows the block is new.
  4. Searches CloudTrail and surfaces the UpdateRuleGroup call that added the deny rule, identifying the user, role, and timestamp approximately one minute before the drops began.
  5. Reports the root cause as that manual rule-group change. Recommends removing the deny entry or adding an allow exception and enabling FirewallPolicyChangeProtection to prevent unauthorized changes.
  6. Presents this as a plan you review and apply, not an automatic change.

In the DevOps Agent Operator Web App view, the agent first restates the Alarm-1 trigger and confirms the firewall is dropping packets above the threshold (Figure 4).

Figure 4: Scenario 1 – The symptom

Figure 4: Scenario 1 – The symptom

Next, the agent identifies the root cause: a manual update to the rg-domain rule group that added a domain deny rule (SID 2000002) shortly before the alarm fired, blocking TLS connections to the ELB endpoint (Figure 5).

Figure 5: Scenario 1 – The root cause

Figure 5: Scenario 1 – The root cause

Finally, the agent presents a mitigation plan, recommending you remove the problematic deny rule (SID 2000002) to restore connectivity (Figure 6).

Figure 6: Scenario 1 – The mitigation plan

Figure 6: Scenario 1 – The mitigation plan

Note: In a real-world environment, this type of rule typically exists for a reason. Before removing it, verify whether it was intentional but scoped too broadly. If so, refine the rule to block only unauthorized endpoints rather than removing it entirely.

Confirm recovery. Apply the change the agent recommends. After the deny entry is gone, DroppedPackets falls back to baseline, Alarm-1 clears, and the card returns to green. Move on to Scenario 2.

Scenario 2. Stateless rule priority misconfiguration

At baseline, the rg-stateless-priority stateless rule group keeps the allow rule at priority 100 and the drop rule at 200 for the test class, TCP destination port 9142. The workload opens a TCP connection to the test endpoint on this port. Lower priority numbers evaluate first, so the allow rule wins. This scenario uses port 9142 instead of 443 to demonstrate a stateless rule, which matches on the packet’s 5-tuple (protocol, ports, addresses) rather than application content.

Introduce the change. Invert the two rule priorities so the drop rule evaluates before the allow rule. This is the kind of change a rushed rule edit can introduce.

To invert the stateless rule priorities

  1. Go to the Amazon VPC console.
  2. In the navigation pane, under Network Firewall, choose Network Firewall rule groups.
  3. Choose the rg-stateless-priority rule group to open its details page.
  4. In the Rules section, choose Edit.
  5. Raise the (Action: Pass) rule’s priority number so it sits after the (Action: Drop) rule, then choose Save. For example, change the (Action: Pass) rule from 100 to 300 (any number higher than the drop rule’s 200 works). You only need to move one rule, and using 300 avoids a clash with the drop rule that already sits at 200. Network Firewall evaluates the lowest priority number first, so the (Action: Drop) rule at 200 now wins for this traffic class, ahead of the (Action: Pass) rule at 300.
Figure 7: Scenario 2 – Rule priority change blocking the traffic class

Figure 7: Scenario 2 – Rule priority change blocking the traffic class

What happens. The drop rule now wins, the TCP connection to the test endpoint on port 9142 times out, the StatelessRuleFailures metric climbs above baseline, and Alarm-2 moves to ALARM. The Scenario 2 card reads DROPPED (with the condition Stateless rules dropping the monitored traffic class), while the Scenario 1 and Scenario 3 cards stay Healthy (Figure 8). On the topology, the alarm pipeline from CloudWatch through Amazon SNS and Lambda to DevOps Agent and the workload-to-firewall inspect lines both turn amber, which the legend defines as collateral / alarm active, because the packets are now dropped at the firewall. To demonstrate the resulting failure, the TLS :9142 line from the internet gateway to the test endpoint is shown in red, which the legend defines as dropped (root cause).

Figure 8: Scenario 2 active

Figure 8: Scenario 2 active

Let DevOps Agent investigate. A stateless drop happens before traffic reaches the stateful inspection engine, so it produces no ALERT log entries. The agent turns to configuration and flow logs instead:

  1. Reads the stateless rule group state and finds the drop rule at the lower priority number, ahead of the pass rule, so the drop evaluates first.
  2. Reads the flow logs and sees passed packets drop to zero within a minute of the change.
  3. Searches CloudTrail and surfaces the UpdateRuleGroup call that inverted the priorities, identifying the user, role, and timestamp about a minute before the alarm.
  4. Reports the root cause as that priority inversion. Recommends removing the redundant drop rule and managing the rule group through infrastructure-as-code (IaC) to prevent manual misconfigurations.
  5. Presents this as a plan you review and apply, not an automatic change.

In the DevOps Agent Operator Web App view, the agent first restates the Alarm-2 trigger and confirms that a workload connectivity health check is failing because the firewall’s stateless rules are dropping egress (Figure 9).

Figure 9: Scenario 2 – The symptom

Figure 9: Scenario 2 – The symptom

Next, the agent identifies the root cause, using the rule-group state and CloudTrail to pinpoint the conflicting DROP/PASS rules, where the new DROP rule’s lower priority number makes it match first (Figure 10).

Figure 10: Scenario 2 – The root cause

Figure 10: Scenario 2 – The root cause

Finally, the agent presents a mitigation plan, recommending you remove the conflicting DROP rule at priority 200 to restore traffic flow (Figure 11).

Figure 11: Scenario 2 – The mitigation plan

Figure 11: Scenario 2 – The mitigation plan

Confirm recovery. Apply the change the agent recommends. After the allow rule is ahead of the drop rule again, Alarm-2 clears and the card returns to green. Move on to Scenario 3.

Scenario 3. Asymmetric cross Availability Zone routing drop

At baseline, the protected subnet in each Availability Zone routes its egress through the firewall endpoint in that same Availability Zone , and the matching return route uses that same endpoint. One endpoint sees both directions of the flow, so the stateful engine completes the handshake. The workload runs in the protected subnet in us-east-1a (CIDR 10.0.4.0/24), so at baseline its egress and its return both use the us-east-1a firewall endpoint.

Introduce the change. Make the flow asymmetric by sending egress out one Availability Zone endpoint while the return comes back through the other. This takes two route edits, and both are required. With only the first edit the flow can still complete, so the alarm will not trigger until both are saved. It makes no firewall-policy change, mirroring a real multi-Availability-Zone routing mistake.

To create asymmetric cross Availability Zone routing

  1. Go to the Amazon VPC console and choose Route tables in the navigation pane.
  2. Flip the egress. Select the NfNetworkStack/SampleVpc/protectedSubnet1 route table (the us-east-1a protected subnet, where the workload runs). On the Routes tab, choose Edit routes. Its 0.0.0.0/0 route currently targets the us-east-1a firewall endpoint. For the target, choose Gateway Load Balancer Endpoint and select the us-east-1b firewall endpoint, then choose Save changes.
  3. Move the return. Select the NfNetworkStack/SampleVpc/publicSubnet2 route table (the us-east-1b public subnet, where egress now exits). Choose Edit routes, then Add route. For the destination enter the workload CIDR 10.0.4.0/24. For the target, choose Gateway Load Balancer Endpoint and select the us-east-1a firewall endpoint. Choose Save changes.

After both edits, a flow’s egress leaves through the us-east-1b endpoint while its return is directed to the us-east-1a endpoint. Neither endpoint sees the whole flow.

Figure 12: Scenario 3 routing change breaking the flow’s symmetry

Figure 12: Scenario 3 routing change breaking the flow’s symmetry

What happens. A new connection leaves through one endpoint. Its return arrives at the other endpoint, which never saw the connection open, so the handshake fails. Unlike Scenarios 1 and 2, this affects the whole subnet, so all egress stops and Alarm-2 and Alarm-3 both move to ALARM. The AWS/NetworkFirewall DroppedPackets alarm (Alarm-1) stays quiet because no endpoint is making a drop decision. The flow is lost to asymmetric routing rather than counted as a firewall drop. This is why monitoring application connectivity matters. A routing fault is invisible to the firewall’s own drop counter. On the status page, the Scenario 2 card reads DROPPED (with the condition “Stateless rules dropping the monitored traffic class”) and the Scenario 3 card reads DROPPED (with the condition Return traffic dropped by asymmetric cross-Availability-Zone routing), while the Scenario 1 card stays Healthy (Figure 13). On the topology, the alarm pipeline from CloudWatch through Amazon SNS and Lambda to DevOps Agent and the workload-to-firewall inspect lines both turn amber, which the legend defines as collateral / alarm active, while the egress path from the firewall through the NAT gateway and the TLS :9142 and HTTPS · routing lines to the test endpoint turn red, which the legend defines as dropped (root cause).

Figure 13: Scenario 3 – The status page during a path-wide outage

Figure 13: Scenario 3 – The status page during a path-wide outage

Let DevOps Agent investigate. Both Alarm-2 and Alarm-3 fire in the same datapoint. DevOps Agent recognizes them as linked and merges them into a single investigation:

  1. Reads the flow logs and sees bidirectional TLS connections stop abruptly, with only one-way traffic remaining and no flows reaching the established state.
  2. Reads the firewall metrics and sees received and passed packets shift from one Availability Zone to the other at the moment of the change.
  3. Calls DescribeRouteTables and finds the egress route pointing at one Availability Zone firewall endpoint while the return route points at the other.
  4. Searches CloudTrail and surfaces the ReplaceRoute and CreateRoute calls by the same user, about a minute before both alarms fired.
  5. Reports the root cause as that asymmetric routing change. Recommends restoring symmetric same-Availability-Zone routing so egress and return traverse the same endpoint.
  6. Presents this as a plan you review and apply, not an automatic change.

A mitigation plan is a recommendation you review, not an automatic change, and the right fix depends on the intended design. Restoring symmetric routing can mean sending the workload subnet’s egress back through its own-Availability-Zone firewall endpoint (this sample’s architecture) or, in a design that doesn’t inspect this path, back through a NAT gateway. The agent infers a plausible target from what it can observe, so review the specific route it proposes against your intended topology before you apply it. (Connecting your pipeline or infrastructure-as-code, covered in the next section, lets the agent recommend the target that matches your design.)

In the DevOps Agent Operator Web App view, the agent restates the Alarm-3 (AsymmetricFlowFailures) trigger and confirms the workload’s egress to a monitored endpoint is being blocked by the Network Firewall (Figure 14).

Figure 14: Scenario 3 – The symptom

Figure 14: Scenario 3 – The symptom

Next, the agent identifies the root cause: manual route table changes that created cross-AZ asymmetric routing through the network firewall, breaking its symmetric routing requirement (Figure 15)

Figure 15: Scenario 3 – The root cause

Figure 15: Scenario 3 – The root cause

Finally, the agent presents a mitigation plan, recommending you restore symmetric routing by pointing protectedSubnet1‘s default route back to the same Availability Zone firewall endpoint, so one endpoint sees both directions of the flow again (Figure 16).

Figure 16: Scenario 3 – The mitigation plan

Figure 16: Scenario 3 – The mitigation plan

Confirm recovery. Apply the change the agent recommends, after checking the route target matches your intended design. After the workload subnet’s egress and return use the same Availability Zone firewall endpoint again, the control probe recovers, the alarms clear, and every card returns to green.

Further considerations

In production a single change can trigger several alarms at the same time, as Scenario 3 shows. DevOps Agent links related investigations and works them as one, so you review a single root cause. You can validate the linked findings or unlink an alarm to investigate it independently. If you would rather collapse alarms before they reach the agent, you can add correlation logic in the bridge Lambda function, buffering and grouping by firewall. You can also add email, Amazon Simple Queue Service (Amazon SQS), or HTTP subscribers to the SNS topic, or add the webhook Lambda function to a topic you already run. DevOps Agent produces a mitigation plan but does not change your environment on its own.

You can also give the agent more to work with. DevOps Agent connects to source repositories and CI/CD pipelines, integrating with GitHub (including GitHub Enterprise Server and GitLab Self-Managed through a private connection). It can associate AWS resources with deployments of AWS CloudFormation, AWS CDK, Amazon Elastic Container Registry (Amazon ECR) images, and Terraform. With deployed configuration and recent deployment events in view, the agent correlates the disruption against the change that introduced it and recommends a fix matching your intended design. For this sample, that means recommending the workload subnet’s own Availability Zone firewall endpoint rather than a generic symmetric path.

DevOps Agent also supports proactive incident prevention. It analyzes patterns across past investigations and delivers recommendations to prevent similar issues from recurring, including governance recommendations that strengthen deployment processes and pipeline controls. For Network Firewall rule changes, this means the agent can recommend guardrails for your CI/CD pipeline based on the classes of misconfigurations it has already resolved. You can access these recommendations through the Improvements page in the DevOps Agent Operator Web App.

Clean up

Clean up the environment with one command.

bash scripts/destroy.sh

It reverts any active scenario, runs cdk destroy for all stacks, and sweeps for stragglers by the Project = nf-devops-agent tag. The main cost drivers are the two Network Firewall endpoints, the NAT gateways (one in the main VPC for each Availability Zone, one in the test-endpoint VPC), and the test endpoint’s load balancers. Each of these bills at an hourly rate for as long as it’s provisioned, whether or not traffic is flowing, so a stack left running continues to accrue charges around the clock even while idle. Running the scenarios and tearing the stack down the same day limits the cost to a few active hours rather than days of idle hourly charges.

Conclusion

In this post, we showed you how AWS DevOps Agent accelerates troubleshooting for three common network firewall connectivity issues. The first was a domain deny list. The second was a stateless priority inversion. The third was an asymmetric cross-AZ routing drop. For each one, DevOps Agent investigated the drop and returned a root cause with a mitigation plan you approve before applying. The first scenario triggered on a prebuilt Network Firewall metric, and the other two on application health metrics. That shows both ways to alarm on a firewall problem through one pipeline.

The pattern isn’t specific to Network Firewall. The same flow fits any service that emits CloudWatch metrics and logs, such as AWS WAF, security groups, and network ACLs. Clone the sample repository to explore the solution, then apply what you learn to your own firewall, application, and alarms. For more details, see the AWS Network Firewall Developer Guide and the AWS Network Firewall pricing page. Start with the Getting Started with AWS DevOps Agent guide to connect your first webhook.

Salman Ahmed

Salman is a Senior Technical Account Manager at AWS, specializing in helping customers design, implement, and optimize their AWS environments. He combines deep networking expertise with a passion for exploring emerging technologies to help organizations get the most out of their cloud investments. Outside of work, he enjoys photography, traveling, and watching his favorite sports teams.

Automated Incident Remediation with AWS DevOps Agent and Kiro CLI

Post Syndicated from Jishnu Dasgupta original https://aws.amazon.com/blogs/devops/automated-incident-remediation-with-aws-devops-agent-and-kiro-cli/

Introduction

Automated incident remediation – turning investigation findings into deployed fixes without manual toil – is the next frontier for operations teams running distributed workloads on AWS. Today, when an incident fires at 2 AM, the on-call engineer must correlate telemetry across Amazon CloudWatch, deployment pipelines, and application logs, then manually write and deploy a fix – a process that routinely takes hours. AWS DevOps Agent addresses the first half by autonomously investigating incidents, identifying root causes, and generating mitigation plans in minutes. During preview, customers and partners reported up to 75% lower MTTR, 80% faster investigations, and 94% root cause accuracy.

But investigation and mitigation recommendations are only half the story. Someone still has to read the findings, write the fix, test it, and deploy it. What if that second half could be automated too?

In a previous post, Leverage Agentic AI for Autonomous Incident Response with AWS DevOps Agent, we demonstrated how to configure AWS DevOps Agent to monitor your applications, trigger autonomous investigations, and follow best practices for production deployments. We also published this code sample which demonstrates how investigations could be wired to be triggered automatically when a Amazon CloudWatch alarm is raised. These two articles now allow you to trigger AWS DevOps Agent investigation on a Amazon CloudWatch alarm and produce a mitigation plan.

In this post, we demonstrate how to integrate AWS DevOps Agent mitigation plan output with Kiro CLI – running in headless mode on AWS CodeBuild – to close the remediation loop end-to-end. When AWS DevOps Agent completes a mitigation analysis, an event-driven pipeline automatically routes the findings to Kiro CLI, which applies the fix to your codebase, creates a pull request for human review, and triggers deployment upon approval. The result: L1/L2 incidents go from detection to deployed fix with minimal manual intervention – the only human touchpoint is the pull request approval.

We walk through the complete solution using a sample CloudFormation application, including the infrastructure code, anomaly generation scripts, event routing, and the Kiro CLI steering configuration that makes it all work. All source code is available in the accompanying aws-samples repository.

Solution Overview

Consider a typical web application running on AWS — a frontend behind an Application Load Balancer, backend compute on Amazon EC2, and an Amazon RDS database, with source code and CloudFormation templates in AWS CodeCommit. When something goes wrong in this environment, the solution chains two AWS frontier agents —AWS DevOps Agent for autonomous investigation and mitigation, and Kiro CLI for automated code remediation — through a fully serverless event-driven bridge to take the application from incident to deployed fix.

Solution Architecture

Fig 1 – Solution architecture

How it works

  1. An incident occurs – Your application experiences an issue – high CPU utilization, elevated error rates, slow response times. Amazon CloudWatch alarms fire.
  2. DevOps Agent investigates – AWS DevOps Agent, which has your application onboarded into an Agent Space, autonomously correlates metrics, logs, and deployment history to identify root cause and generate a mitigation plan.
  3. EventBridge routes the signal – An Amazon EventBridge rule captures Mitigation Completed events (source: aws.aidevops) and invokes a AWS Lambda function.
  4. Lambda extracts and queues – The AWS Lambda function calls the AWS DevOps Agent API to retrieve the mitigation summary and execution plan, then publishes the payload to Amazon SQS queue.
  5. CodeBuild runs Kiro CLI – When a message arrives in the Amazon SQS queue, a AWS Lambda function with an SQS event source mapping triggers a AWS CodeBuild execution, passing the message content as an environment variable. AWS CodeBuild runs Kiro CLI in headless mode (–no-interactive –trust-tools=read,write,grep,shell), using the mitigation payload as a remediation prompt.
  6. Kiro CLI applies the fix – Guided by a steering file that describes the repository structure and remediation conventions, Kiro CLI modifies the CloudFormation template or application code, commits to a feature branch, and creates a pull request.
  7. Human approves, pipeline deploys – A developer reviews the pull request. Upon approval and merge, the associated deployment pipeline gets triggered to execute the change.

Prerequisites

To follow along with this walkthrough, you need:

  • An AWS account for AWS DevOps Agent access
  • An Agent Space configured
  • Kiro CLI with a Pro, Pro+, or Power subscription (required for headless mode API keys)
  • AWS CLI configured with appropriate credentials
  • The sample repository pushed to your account’s AWS CodeCommit repository

Once completed, follow along the Readme file to setup the components which allow you to implement and execute the above architecture. The sections below provide an explanation of the components that have been built to support the architecture.

Capturing mitigation events

AWS DevOps Agent publishes lifecycle events to the Amazon EventBridge default event bus whenever an investigation or mitigation changes state. Each event uses the source aws.aidevops and a detail-type that identifies the specific like Mitigation Completed, Investigation Completed, or Mitigation Failed. The post focuses on a single signal: the moment a mitigation finishes successfully.

EventBridge rule and Lambda extraction

An Amazon EventBridge rule matching the Mitigation Completed detail-type invokes a AWS Lambda function. The event payload contains metadata (agent_space_id, task_id, and execution_id) which allows the AWS Lambda function to call the AWS DevOps Agent and extracts two key objects: the mitigation summary (what action to take and why) and the execution plan (step-by-step instructions). It publishes this structured payload to an Amazon SQS queue for downstream processing.

Headless remediation with Kiro CLI

With mitigation payloads landing in the Amazon SQS queue, we need a compute environment that can check out the application and infrastructure repository, run Kiro CLI agent against the codebase, and push changes back. AWS CodeBuild is a natural fit — it provides on-demand compute, integrates natively with AWS CodeCommit and requires no persistent infrastructure.

Kiro CLI 2.0 introduced headless mode, which allows it to run programmatically in deployment pipelines without an interactive terminal. You authenticate with an API key (stored in AWS Secrets Manager), pass a prompt, and Kiro CLI executes end-to-end — same tools, same agents, same capabilities as the interactive experience.

How CodeBuild orchestrates the fix

When a message arrives in the Amazon SQS queue, a trigger AWS Lambda function starts a AWS CodeBuild execution, passing the Amazon SQS message body as an environment variable. The AWS CodeBuild buildspec follows a straightforward sequence:

  1. Install : Installs Kiro CLI and configures the environment. The KIRO_API_KEY is pulled automatically from AWS Secrets Manager ,never hardcoded.
  2. Generate prompt : A Python script converts the structured mitigation payload into a natural-language remediation prompt. It inspects the content to classify whether the change targets infrastructure (or application code, then generates a focused prompt with the action, reasoning, and specific instructions.
  3. Create feature branch : Checks out a new branch named after the agent space and execution IDs for traceability.
  4. Run Kiro CLI : Invokes Kiro CLI chat –no-interactive –trust-tools=read,write,grep,shell with the generated prompt. The –trust-tools flag auto-approves specific tool categories following least-privilege, since there is no human to confirm.
  5. Validate and commit : Guardrails check the changes: file count limits, protected file detection, Python syntax validation (py_compile), and YAML linting. If all checks pass, the changes are committed and pushed.
  6. Create pull request : Creates an AWS CodeCommit pull request with the mitigation action as the title and the AWS DevOps Agent reasoning in the description.

The steering file

What makes Kiro CLI effective at remediation – rather than just generating generic code – is the steering file. Steering gives Kiro persistent knowledge about your project: repository structure, coding conventions, and decision frameworks.

For this solution, the steering file serves as the guardrails for automated remediation. It defines:

  • Repository structure – Maps each directory to its purpose.
  • Decision framework – Rules for classifying changes as infrastructure vs. application.
  • Scope constraints – Maximum 3 files per remediation, no new files, no new dependencies, no deletions.
  • Protected files – The buildspec, infrastructure pipeline templates, bridge code, and steering files themselves are explicitly off-limits.
  • Fail-safe – If the prompt is ambiguous or Kiro cannot determine what to change, it makes no changes rather than guessing.

This steering file is committed to the repository, so every AWS CodeBuild execution picks it up automatically. It ensures Kiro CLI makes targeted, predictable changes rather than broad refactors.

From pull request to deployment

At this point, the automated pipeline has done its work – Kiro CLI has analyzed the mitigation plan, modified the appropriate files, and created a pull request on a feature branch. The pull request description includes what was changed, why (directly from the AWS DevOps Agent’s reasoning), and the agent space and execution IDs for full traceability back to the original incident.

This is where the human-in-the-loop gate comes in. A developer reviews the pull request -verifying that the change is correct, scoped appropriately, and safe to deploy. This approval step is deliberate: while we trust the agents to investigate, analyze, and propose fixes, a human makes the final deployment decision.

Once the pull request is approved and merged into the main branch, the deployment pipelines implement the approved changes in the target environment.

The entire cycle – from CloudWatch alarm to deployed fix – completes in minutes rather than hours, with the only manual step being the pull request review. For organizations handling high volumes of L1/L2 incidents, this translates directly into reduced operational toil and faster recovery.

Cleanup

To avoid ongoing charges, remove the resources created during this walkthrough. Refer to the Readme for the complete teardown sequence.

Conclusion

In this post, we demonstrated how to integrate AWS DevOps Agent mitigation outputs with [1] Kiro CLI to build a closed-loop incident remediation pipeline. By connecting these two frontiers agents’ operations teams can go from incident detection to deployed fix with a single human touchpoint: the pull request approval.

This approach delivers measurable impact for enterprise operations:

  • Reduced MTTR – L1/L2 incidents that previously required hours of manual investigation and remediation can now resolve in minutes.
  • Improved operator productivity – Engineers shift from reactive firefighting to reviewing and approving targeted, AI-generated fixes.
  • Consistent remediation – Steering files codify your team’s conventions and decision frameworks, ensuring every automated fix follows the same standards regardless of when or how often incidents occur.

Ready to get started? Clone the aws-samples repository for the complete implementation, visit the AWS DevOps Agent documentation to configure your first Agent Space, and explore the Kiro CLI documentation to learn more about steering-file-driven code generation. Have questions or want to share how you’ve adapted this pattern? Leave a comment below or open an issue in the repository

Jishnu Dasgupta

Jishnu Dasgupta

Jishnu Dasgupta is a Senior Solutions Architect at AWS who specializes in manufacturing and automotive domain. His focus areas are building, migrating and modernizing applications on AWS. He leverages his expertise and experience to help AWS customers build optimized, scalable and fit to purpose architecture on AWS.

Chetan Dharma

Chetan Dharma

Chetan Dharma is a Senior AI Solution architect with 20+ years of experience driving technology transformation for large-scale global enterprises. He has worked across investment banking, logistics, automative, and digital native businesses — progressing from hands-on engineering to architecture to advising AI transformation

Automating cross-repo documentation with GitHub Agentic Workflows

Post Syndicated from David Pine original https://github.blog/ai-and-ml/github-copilot/automating-cross-repo-documentation-with-github-agentic-workflows/


“Where are the docs?” It’s a question nobody on a product team enjoys answering. The honest reply is usually some variant of “behind.” A writer is staring at a closed pull request, trying to reverse-engineer what changed. The pull request’s author has already moved on. By the time the doc actually publishes, the feature has shipped, sometimes more than once.

That used to be us on the Aspire team (we’re a small team of 10 building dev tools for distributed apps). A few months back, we were trying to figure out how to safely bring AI into automations we already trusted. That’s when we discovered GitHub Agentic Workflows. I started bolting prototypes into microsoft/aspire.

Here’s what that bought us, in numbers pulled straight out of GitHub: for Aspire 13.3 and 13.4, 82 feature-docs pull requests merged at a median of 44.8 hours after the product pull request, every one of them reviewed by the engineer who shipped the feature. No new headcount. No process retraining. Just a different way of asking “who writes this?”

🔒 The constraint: cross-repo automation is the hard part

Our product lives in microsoft/aspire and our docs site lives in microsoft/aspire.dev—different repo, deploy target, and review chain. Most teams figure out same-repo automation pretty quickly; cross-repo automation is where things get sharp. Broad repo-scoped tokens belong in a museum, and any responsible security posture (ours included) restricts them accordingly. That’s a good thing. It’s also a real bottleneck if the place where you write the docs isn’t the place where you write the code.

The default workflow for years was:

  1. Engineer ships a feature in microsoft/aspire.
  2. Docs writer notices weeks later.
  3. Docs writer opens the pull request, reads the diff, and pings the engineer to clarify what changed.
  4. Engineer is on the next feature, vaguely remembers, replies with half the picture.
  5. Docs draft ships, sometimes against a release that’s already out.

This is the reverse-engineering tax. We needed automation that crossed repos without handing an agent a write-everywhere token. GitHub Agentic Workflows turned out to be the answer.

🤖 Why GitHub Agentic Workflows

GitHub Agentic Workflows is a project from the GitHub Next team that I keep describing to people as “GitHub Actions, but with a model as the work-item processor and guard rails that satisfy security review.” That’s reductive, but it’s close.

The shape of it:

  • You author a workflow as a single markdown file (.github/workflows/my-thing.md). YAML-style frontmatter on top, an English-language prompt underneath.
  • You run GitHub Agentic Workflows compile, and it generates a sibling .lock.yml (a normal GitHub Actions workflow) that you commit alongside.
  • At runtime, the workflow runs an agent against your prompt with a constrained toolset.
  • Critically, the agent doesn’t write to GitHub directly. It emits intent (a JSON blob describing the pull requests, issues, and comments it wants to create), and a separate, narrowly scoped job (the safe-outputs handler) materializes that intent against a per-workflow GitHub app.

That last bullet is the unlock. The agent gets read access and a prompt. Writes go through a tiny verifiable pipeline with explicit allow-lists. Security review nods. We ship.

💚 A small aside: kindred stacks

I love when the tools you’re using to build are built with the same tools you’re using to build with. The GitHub Agentic Workflows docs are built with Astro and Starlight. So is aspire.dev—Astro with Starlight, dressed up with the wider Starlight plugin ecosystem (astro-mermaid, starlight-llms-txt, starlight-sidebar-topics, starlight-image-zoom, the gorgeous @catppuccin/starlight theme, and more. Shout-out to Chris Swithinbank and the Starlight maintainers, the entire ecosystem feels designed by people who genuinely care).

There’s a real kinship there. The tool we use to automate docs and the docs site we automate into share the same foundation. Convenient, because the Mermaid sequence diagram in the next section renders the exact same way in both worlds.

The end-to-end pipeline

Here’s the flow we landed on. The protagonist is a workflow called pr-docs-check.md living in microsoft/aspire.

Sequence diagram showing an automated docs workflow: merging a feature pull request in microsoft/aspire triggers a GitHub Actions check that has an agent draft the documentation, open a draft pull request in microsoft/aspire.dev, and request SME review—so docs ship with the feature.

A run starts on pull_request: closed against main or release/*, gated by merged == true. From there, the workflow first runs a deterministic target branch resolver in plain bash before the agent ever wakes up:

  1. Pull request milestone title (e.g. 13.4 → release/13.4 on aspire.dev).
  2. Linked-issue milestone title (parse Fixes/Closes/Resolves #N from the body, fetch each issue, take the first non-empty milestone).
  3. Pull request base ref, if it matches release/X.Y[.Z].
  4. Fall back to main.

This is the linchpin. Milestones in the product repo map cleanly to release branches in the docs repo. When the agent finally runs, it knows exactly where the docs should land without any creative writing about target branches or guessing.

The agent reads the diff, scans linked issues, and decides: does this need docs? If yes, it drafts the actual content in a checked-out microsoft/aspire.dev workspace, following our existing doc-writer skill (voice, MDX conventions, Starlight components). It then emits a create_pull_request safe-output and hands off.

The safe-outputs handler takes over:

  • Title prefix: [docs]
  • Label: docs-from-code
  • draft: true (we never auto-merge)
  • Base branch: agent-supplied, restricted to main or release/*
  • Target repo: microsoft/aspire.dev
  • Reviewer: the SME identified from the source pull request’s reviews—i.e., whoever the product team trusted to approve the feature, now gets asked to approve the doc for that feature.

A companion job posts a marker comment back on the source pull request with the docs pull request link and minimizes any older pr-docs-check comments on re-run. The engineer who just hit Merge gets a notification within a few minutes: “Here’s the docs draft. Look it over?”

🔐 The safe-outputs contract

The whole security story comes down to a small, boring stretch of frontmatter:

tools: 
  github: 
    toolsets: [repos, issues, pull_requests] 
    min-integrity: approved          # only run pinned, integrity-checked actions 
    allowed-repos: 
      - microsoft/* 
    github-app: 
      app-id: ${{ secrets.ASPIRE_BOT_APP_ID }} 
      private-key: ${{ secrets.ASPIRE_BOT_PRIVATE_KEY }} 
      owner: "microsoft" 
      repositories: ["aspire.dev", "aspire"] 

safe-outputs: 
  create-pull-request: 
    title-prefix: "[docs] " 
    labels: [docs-from-code] 
    draft: true                      # human-in-the-loop, always 
    base-branch: main 
    allowed-base-branches: [main, release/*] 
    target-repo: "microsoft/aspire.dev" 
    protected-files: blocked         # AGENTS.md, manifests, security config: hands off 
    fallback-as-issue: true 

That’s the deal in plain text. The agent gets a GitHub App token whose installation is scoped to exactly two repositories—the product repo and the docs repo—and nothing else in the org is reachable. It can only land pull requests against main or release/*. AGENTS.md and dependency manifests are off-limits by policy. If the pull request creation fails (network blip, conflict, anything), the framework falls back to filing an issue, so nothing is silently dropped.

This is the part security review actually liked. The agent’s reasoning is fuzzy. The action surface is not.

📊 By the numbers

Here are the stats from a rolling 30-day window (May 3 – June 2, 2026) spanning the back end of the Aspire 13.3 release and the run-up to 13.4:

Metric  Value 
Product pull requests merged in microsoft/aspire  396 (338 main / 50 release/13.3 / 8 release/13.2) 
pr-docs-check workflow runs  396 
Draft docs pull requests created on microsoft/aspire.dev  82 
  – Merged  82 (100%) 
  – Closed without merge 
  – Still open 
Docs pull requests target branches  52 → release/13.3, 27 → release/13.4, 3 → main 
Median time-to-merge (docs)  44.8 hours 
Merged within 24 h / 7 days  38% / 96% 

Note: Numbers captured at the time of writing; the workflows keep running, so the totals only go up. 

A few of those numbers deserve a second look:

  • 396 runs → 82 pull requests is not a defect. The workflow runs on every merged pull request; most of them are internal refactors, test fixes, or dependency bumps with no user-facing surface. The agent saying “no docs needed” 300+ times is a feature.
  • 100% merge rate says the agent’s docs picks are right. The tighter prompt we shipped after the v1 false-positive phase is paying off.

✅ What worked, what didnt

What worked

  • Milestone → release-branch mapping. This was the single highest-leverage choice we made. Engineers already set milestones on pull requests and issues; we got accurate target-branch routing for free.
  • Draft-only, SME-as-reviewer. The agent never merges. The engineer who shipped the feature is the one who confirms the docs are right. We’ve stopped reverse-engineering features at the doc layer. The engineer just tells the docs draft what to say, in the place where they already are.
  • Scoped GitHub app per workflow. Each workflow gets its own app token with explicit repo and permission scopes. Security review approved. We approved too; the first time we needed to rotate keys.
  • protected-files: blocked. The agent cannot touch AGENTS.md, package manifests, or repo security config. Period.

What didn’t (at first)

  • ❌ The agent’s “is this docs-worthy?” gate was too generous in the first version. It drafted pull requests for changes that were genuinely internal, such as a CI tweak or a logging refactor. The result: 9 closures of 69 pull requests (≈13%), so we tightened the prompt’s user-facing-change definition and added explicit negative examples (CI, internal helpers, tests-only). Now, the rate is trending down.
  • ❌ Cross-repo pull request creation needed a mirrored checkout pattern that wasn’t obvious from the docs. The agent works in one repo; safe-outputs needs to find the target repo to push a branch. We solved it by checking out microsoft/aspire.dev twice—once as the current workspace, once under _repos/aspire.dev—so the safe-outputs handler can rediscover it deterministically.
  • ❌ Big diffs blow prompt budgets. We pre-extract pull request metadata (linked issues, milestone, base ref) in pre-agent-steps bash, so the agent gets a small, structured summary instead of a giant payload. This is GitHub Agentic Workflow’s designed-in pattern, and it works.

Wrapping up

The changes we made shifted our thinking. A feature wasn’t considered done until the docs were. Docs no longer trail along behind it like a tin can on a string. The engineer’s review is the gate; the bot does the typing.

Critically, this doesn’t replace docs writers; it un-burdens them. Our writers used to spend most of their time reverse-engineering features. Now they spend their time on the things only a human can do well: narrative pages, sample programs, conceptual walkthroughs, the parts of the docs that don’t fall out of a diff. The bot handles the mechanical “this new option was added; here’s the reference page update” work that was never enjoyable for anyone.

Huge thanks to the GitHub Next team for GitHub Agentic Workflows (and for making the safe-outputs primitive a first-class part of the design), and to Chris Swithinbank and the Starlight maintainers for the docs platform we automate into. A genuine thank-you, too, to the security folks whose guardrails forced us to design this the right way the first time. The boring secret of good automation is that strong security constraints make the system more trustworthy and more correct.

If you build a product in one repo and ship docs in another—and especially if you have to do it inside any nontrivial security boundary—GitHub Agentic Workflows is worth a serious look. Start with one workflow, such as pr-docs-check, and watch what happens to your median time-to-docs.

🔗 The other workflows

pr-docs-check is the one I wrote this post about, but it’s not running alone. If you’re curious about the rest, the source is public:

  • milestone-changelog.md: runs every two hours, picks up newly merged pull requests in the active milestone, and maintains a 13.x-Change-log wiki page (new features, improvements, notable bug fixes) with a companion editorial-feedback issue. 346 runs.
  • release-update-support-mdx.md: on a stable Aspire release, drafts a [support] pull request on aspire.dev that updates the support policy page (promotes the new version, demotes the previous one, refreshes the “Last updated” badge).
  • update-integration-data.md: lives in the docs repo; runs pnpm update:all daily, refreshes NuGet metadata + GitHub stats + sample data, and opens a chore: Update integration data PR with supersede-and-close logic for stale runs. 27 runs, eight merged pull requests.
  • repo-pulse.md: a rolling three-day repo dashboard pinned to a single issue and updated in place: recent merges, pull requests awaiting review, new issues, discussion activity. One issue, always fresh.

Happy automating, friends! 🤖🚀

The post Automating cross-repo documentation with GitHub Agentic Workflows appeared first on The GitHub Blog.

Feature Flag Orchestration with AWS DevOps Agent and LaunchDarkly

Post Syndicated from Greg Eppel original https://aws.amazon.com/blogs/devops/feature-flag-orchestration-with-aws-devops-agent-and-launchdarkly/

Introduction

Organizations that use feature flags alongside incident response tooling often connect the two manually. When an outage occurs, engineers must identify which flags are relevant, decide whether to disable them, and coordinate the change across teams. This manual process adds latency at the moment it matters most.

You can use AWS DevOps Agent and its MCP server feature to connect to LaunchDarkly’s hosted MCP server, enabling feature flag recommendations during both proactive deployment review and reactive incident response workflows. Once connected, DevOps Agent can query flag state, read targeting rules, and surface recommendations directly within the workflows where engineers make decisions.

This post walks through two primary use cases:

  1. Pre-deployment review where the release management capabilities in AWS DevOps Agent evaluate changes and a DevOps Agent Skill recommends feature flag coverage before code ships.
  2. Incident response where DevOps Agent queries LaunchDarkly flag state via MCP and recommends containment actions during active incidents.

We also cover the connection architecture, a reusable DevOps Agent Skill for pre-deployment flag validation, and links to get started.

Defense: Release Management and Proactive Flag Recommendations

Five-step sequence diagram of the pre-deployment review workflow: PR Submitted, DevOps Agent Readiness Review Analyzes PR, Flag Gate Skill recommends a LaunchDarkly flag, Recommendation Surfaced, Developer Reviews.

Figure 1: DevOps Agent’s readiness review identifies high-risk PRs and recommends LaunchDarkly feature flag coverage before code ships.

The release management capabilities (now in public preview) in AWS DevOps Agent evaluate code changes before they ship to production.

It performs functional testing in an AWS-managed verification environment, assesses risks to cross-codebase dependencies, evaluates adherence to your organization’s standards and best practices, and mathematically verifies that access control configurations in CloudFormation do not deviate from Well-Architected best practices.

AWS DevOps Agent is designed to be extended and customized to fit your tools, standards, and practices. Using the product’s primitives, you can add Skills that enhance its capabilities. For example, when a high-risk change is identified, a custom Skill can evaluate whether the change has adequate feature flag coverage, operating on deployment metadata and code analysis to identify gaps and surface a recommendation to the developer, such as recommending feature flags with LaunchDarkly when needed.

What the Skill Evaluates

The release readiness flag Skill classifies code changes into risk tiers (Critical, High, Moderate) based on what’s being modified — payments, authentication, database schemas, third-party integrations, new API endpoints, performance-sensitive paths, and more — and recommends feature flags proportional to the risk level.

Screenshot of the AWS DevOps Agent Knowledge panel on the Skills tab, showing a custom skill named "high-risk-feature-flag-recommendations" with a description that reads "Evaluates code changes during release readiness reviews to identify high-risk modifications and recommends wrapping them in LaunchDarkly feature flags for safer rollouts."

Figure 2: The high-risk-feature-flag-recommendations Skill configured in AWS DevOps Agent’s Knowledge panel.

What the Recommendation Includes

When the Skill identifies a gap, it surfaces a recommendation containing:

  • Risk context: Why the change is flagged as high-risk (e.g., “This deployment modifies payment authorization logic across 3 downstream services with no existing rollback mechanism.”)
  • Suggested flag configuration: A proposed LaunchDarkly flag key, variations, and default targeting rules aligned with the deployment plan.
  • Rollout strategy: A recommended phased rollout (e.g., internal users first, then 5% of traffic, then full rollout) that matches the risk profile.
  • Kill-switch behavior: What happens when the flag is turned off — the fallback code path, cleanup considerations, and data consistency implications.

Example Scenario

Consider a team deploying an update to a tax calculation service. The change modifies the tax rate computation logic, affecting all order totals across multiple regions. AWS DevOps Agent evaluates the deployment and classifies it as high-risk. The pre-deployment flag gate Skill then identifies:

  • The change touches critical-path tax calculation code.
  • No feature flag wraps the new computation behavior.
  • The blast radius covers all active checkout sessions.

The Skill surfaces a recommendation: “This deployment modifies tax calculation logic with no existing feature flag coverage. Recommend wrapping the new tax computation in a LaunchDarkly flag (tax-calculation-v2) with a phased rollout targeting internal test accounts first, followed by 5% of production traffic.” 

The developer can then action the recommendation, creating the flag in LaunchDarkly, adjusting the suggested configuration to fit their rollout plan, or noting the justification for proceeding without one as part of the deployment record.

Screenshot of the AWS DevOps Agent Report tab showing a policy violation titled "Checkout pricing changes deployed without a LaunchDarkly feature flag." The report includes risk context, evidence from a repo grep showing no existing flag, a suggested fix with sample Node.js code using the LaunchDarkly SDK, and a recommended phased rollout strategy.

Figure 3: AWS DevOps Agent release management report identifying checkout pricing changes deployed without LaunchDarkly feature flag coverage, including a suggested fix with sample code.

Closing the Loop with Kiro IDE

DevOps Agent’s release management capabilities identify when a deployment needs feature flag coverage. Paired with Kiro IDE, this recommendation becomes actionable without leaving the development workflow.

Kiro connects to LaunchDarkly’s MCP server directly, providing flag integration capabilities during development. When a developer builds a new feature in Kiro, the IDE can query LaunchDarkly via MCP to check whether a flag already exists for that feature and generate code with the flag evaluation built in from the start.

Together, this creates one continuous flow: DevOps Agent identifies the risk and recommends flag coverage → the developer, working in Kiro, generates the flag and wraps the code in a single action → the deployment ships with coverage already in place. No context-switching between tools, no manual flag creation in a separate console.

Developers can also use Kiro’s flag integration independently during feature development, even before a deployment triggers a release management review. The two operate as layered coverage: if Kiro catches it during development, DevOps Agent validates the targeting rules match the rollout plan at deployment time. If the developer bypasses Kiro or uses a different toolchain, DevOps Agent still identifies the gap.

Offense: Flag Recommendations During Incident Response

During an active incident, speed of containment directly affects customer impact. DevOps Agent participates in incident response workflows by querying LaunchDarkly to understand current flag state, then recommending containment actions based on what it finds.

Sequence diagram: Incident Detected, DevOps Agent correlates with flag change, queries LaunchDarkly via MCP (value changed to 30ms from 2000ms), recommends reverting to 2000ms, engineer confirms action.

Figure 4: DevOps Agent identifies a flag change (30ms from 2000ms) as the probable cause, queries LaunchDarkly for state, and recommends reverting the value.

When you detect an incident, DevOps Agent correlates the affected service with recent deployments. It queries LaunchDarkly to identify feature flags associated with those deployments and their current state (enabled, targeting rules, rollout percentage). If a relevant flag is enabled, the agent recommends disabling it as a containment option before suggesting a full rollback.

Flag-based containment provides an alternative containment option that can help reduce the time to resolution. Disabling a flag may return behavior to the previous state, which can be faster than a full deployment rollback in some scenarios

Example Scenario

An alert fires indicating sustained 5XX errors on the bot-service. The on-call engineer engages DevOps Agent, which:

  1. Correlates the HTTP 503 errors with a LaunchDarkly feature flag change: bot-mutation-orchestration-timeout-ms was changed from the default 2000ms to 30ms (the “low latency” variation), applied to all traffic.
  2. Identifies that the 30ms timeout budget is insufficient for inter-service HTTP calls during bot creation and deletion orchestration, which require DynamoDB reads/writes plus IoT Core calls, causing ReadTimeout exceptions.
  3. Recommends reverting the bot-mutation-orchestration-timeout-ms flag to its default variation (2000ms) as the containment action, noting this will restore sufficient timeout budget without requiring a code deployment.

The engineer reviews the recommendation, updates the flag variation in LaunchDarkly, and the error rate returns to baseline within minutes.

Screenshot of the AWS DevOps Agent Root cause tab showing an investigation summary. The Impact section reports bot-service ALB returning sustained 5XX errors since 18:52Z with 136 errors in 10 minutes. The Root causes section, highlighted with a red border, identifies that the LaunchDarkly feature flag "bot-mutation-orchestration-timeout-ms" was changed to 30ms from the default 2000ms, causing ReadTimeout exceptions.

Figure 5: AWS DevOps Agent investigation summary identifying a LaunchDarkly feature flag timeout change as the root cause of sustained 5XX errors

Step-by-Step Mitigation Plans

When DevOps Agent identifies a root cause, it generates a structured mitigation plan with concrete, executable steps. Rather than a generic recommendation, the agent provides:

  1. Prepare — Document the current error baseline (with ready-to-run CLI commands, e.g., CloudWatch get-metric-statistics) and confirm the problematic configuration is still active before making changes.
  2. Execute — Revert the specific change (in this case, reverting the LaunchDarkly feature flag bot-mutation-orchestration-timeout-ms from 30ms back to the 2000ms default) with clear instructions on which variation to target.
  3. Verify — Validate that error rates return to baseline after the change, confirming the mitigation was effective.

Each step includes sub-steps with specific commands, API paths, and success criteria — giving the on-call engineer a clear, auditable runbook rather than a vague recommendation.

Screenshot of the AWS DevOps Agent Mitigation plan tab showing a plan titled "Revert LaunchDarkly feature flag 'bot-mutation-orchestration-timeout-ms' from 30ms to 2000ms default value." The plan includes Step 1: Prepare, with sub-steps to document the current 5XX error baseline using an AWS CLI command and confirm the flag is still serving the problematic 30ms value.

Figure 6: Structured mitigation plan generated by AWS DevOps Agent with executable steps to revert the feature flag and verify resolution.

Below, the LaunchDarkly targeting configuration shows the bot-mutation-orchestration-timeout-ms flag with its available variations. During the incident, the engineer reverted from the “low latency” variation back to “default” to restore the 2000ms timeout budget.

Screenshot of the LaunchDarkly console showing the targeting configuration for the "bot-mutation-orchestration-timeout-ms" flag in the Production environment. The flag is set to Off, serving the "default" variation to all traffic. A dropdown menu displays the available variations: 1, 0, default (selected), low latency, and moderate.

Figure 7: LaunchDarkly targeting configuration for the bot-mutation-orchestration-timeout-ms flag showing available variations including the default and low latency values.

Connecting to LaunchDarkly via MCP

As described in the introduction, DevOps Agent uses its MCP server feature to connect to LaunchDarkly’s hosted MCP server. This section covers the architecture and setup steps.

LaunchDarkly’s MCP server exposes flag management operations as agent-callable tools through the Model Context Protocol (MCP) standard. DevOps Agent connects as a client, giving it the ability to query flag state, read targeting rules, and list flags by project or environment without custom integration code.

Architecture

The connection follows this flow:

  1. DevOps Agent identifies a need for flag-related context (e.g., during incident response).
  2. DevOps Agent calls LaunchDarkly’s hosted MCP server using standardized MCP tool definitions.
  3. LaunchDarkly MCP Server translates the request into LaunchDarkly API calls and returns structured responses (flag state, targeting rules, rollout percentages).
  4. DevOps Agent uses the response to formulate recommendations presented to the engineer.

Registration and Configuration

To set up the connection:

  1. Register LaunchDarkly’s hosted MCP server endpoint with DevOps Agent.
  2. Configure authentication credentials (LaunchDarkly API key with appropriate scopes).
  3. Validate connectivity by running a test flag query.

For the full setup walkthrough, including detailed configuration steps and permissions requirements, refer to LaunchDarkly’s companion blog post (link placeholder).

The same LaunchDarkly MCP server connection is available in Kiro IDE for flag-aware code generation during development; see the Defense section above for how Kiro completes the pre-deployment workflow.

Example Skill: High-Risk Feature Flag Recommendations

AWS DevOps Agent Skills are modular instruction sets that extend the agent’s capabilities with specialized domain knowledge and investigation methodologies tailored to your infrastructure and operational workflows. AWS DevOps Agent supports a subset of the Agent Skills specification. The format is flexible, but this example is structured into the following sections:

  • Risk Classification Criteria — defines what constitutes Critical, High, and Moderate risk changes
  • Feature Flag Recommendation Format — specifies the output structure: flag name, flag type, targeting strategy, and kill switch guidance
  • Example Recommendations — provides reference examples so the agent produces consistent, actionable output
  • Integration Notes — describes how recommendations surface during release readiness reviews
  • What NOT to Flag — explicitly scopes out low-risk changes to reduce noise

Below is the full Skill used in this example:


# High-Risk Code Feature Flag Recommendations

When performing a release readiness review, use this skill to identify high-risk code changes and recommend LaunchDarkly feature flags for safer, controlled rollouts.

## Risk Classification Criteria

Evaluate code changes against these risk categories:

### Critical Risk (Always recommend feature flag)
- **Payment/billing logic** — any changes to checkout, payment processing, subscription handling, or pricing calculations
- **Authentication/authorization** — login flows, session management, permission checks, OAuth/SSO integrations
- **Database schema changes** — migrations, new columns, index changes, especially on high-traffic tables
- **Data deletion or mutation** — bulk updates, cascading deletes, data transformations
- **Third-party API integrations** — new external service dependencies or changes to existing integrations
- **Core business logic** — order processing, inventory management, user registration flows

### High Risk (Strongly recommend feature flag)
- **New API endpoints** — especially public-facing or partner APIs
- **Performance-sensitive paths** — changes to hot paths, caching logic, query optimizations
- **Feature rewrites** — replacing existing functionality with new implementations
- **Concurrency changes** — threading, async processing, queue handling modifications
- **Configuration changes** — environment variables, feature toggles, service endpoints

### Moderate Risk (Consider feature flag)
- **UI changes to critical flows** — checkout pages, login screens, dashboard views
- **Logging/monitoring changes** — new metrics, log format changes, tracing modifications
- **Error handling changes** — exception handling, retry logic, fallback behaviors

## Feature Flag Recommendation Format

When recommending a feature flag, provide:

### 1. Flag Name
Use a descriptive, lowercase, hyphenated name:
- `enable-new-payment-processor`
- `use-v2-auth-flow`
- `rollout-order-service-refactor`

### 2. Flag Type
Recommend the appropriate LaunchDarkly flag type:
- **Boolean** — simple on/off for feature enablement
- **Multivariate** — when you need multiple variations (A/B testing, gradual migrations)
- **Number/String** — for configuration values that might need adjustment

### 3. Targeting Strategy
Recommend an appropriate rollout strategy:
- **Percentage rollout** — start at 1-5%, monitor, then increase (default for most changes)
- **User segment targeting** — internal users first, then beta users, then general availability
- **Environment targeting** — enable in staging/canary before production

### 4. Kill Switch Guidance
Explain what happens when the flag is turned off:
- What code path executes when disabled
- Any cleanup or rollback considerations
- Data consistency implications

## Example Recommendations

### Example 1: Payment Processing Change

**Code Change:** Refactored payment gateway integration to support new processor

**Recommendation:**
```CRITICAL RISK: Payment processing changes detected

Recommend wrapping in LaunchDarkly feature flag:
- Flag name: `enable-stripe-v2-integration`
- Flag type: Boolean
- Default: OFF (use existing payment flow)

Rollout strategy:
1. Enable for internal test accounts first
2. Expand to 1% of production traffic
3. Monitor payment success rates and error logs
4. Gradually increase to 100% over 1-2 weeks

Kill switch behavior: Reverts to existing payment processor immediately. 
In-flight transactions will complete with their original processor.
```

### Example 2: New API Endpoint

**Code Change:** Added new `/api/v2/orders` endpoint with different response format

**Recommendation:**
```HIGH RISK: New API endpoint with breaking response format

Recommend wrapping in LaunchDarkly feature flag:
- Flag name: `enable-orders-api-v2`
- Flag type: Boolean
- Default: OFF (return v1 format)

Rollout strategy:
1. Enable for specific API clients by client_id targeting
2. Coordinate with consuming teams before enabling
3. Run both versions in parallel during migration period

Kill switch behavior: Returns v1 response format. Ensure v1 
serialization logic remains in codebase until flag is permanent.
```

### Example 3: Database Migration

**Code Change:** Adding new index to high-traffic `orders` table

**Recommendation:**
```CRITICAL RISK: Database schema change on high-traffic table

Recommend wrapping dependent code in LaunchDarkly feature flag:
- Flag name: `use-orders-status-index`
- Flag type: Boolean  
- Default: OFF (use existing query patterns)

Rollout strategy:
1. Deploy migration to create index (can be done independently)
2. Deploy code that uses new index behind flag
3. Enable flag in staging, verify query performance
4. Enable in production during low-traffic window
5. Monitor query latency and database load

Kill switch behavior: Queries fall back to non-indexed path.
May see temporary performance degradation but no data loss.
```

## Integration Notes

When the release readiness review identifies high-risk changes:

1. **Surface the risk level** clearly in the review summary
2. **Provide the flag recommendation** with copy-paste ready configuration
3. **Explain the rollout strategy** appropriate for the risk level
4. **Document the kill switch behavior** so operators know what to expect

## What NOT to Flag

Not every change needs a feature flag. Avoid recommending flags for:
- Pure refactoring with no behavior change
- Test file additions or modifications
- Documentation updates
- Dependency version bumps (unless major version with breaking changes)
- Code formatting or linting fixes

Activating the Skill

DevOps Agent loads Skill metadata at the start of each workflow and loads the full Skill content when it determines relevance. To ensure the feature flag Skill is consistently applied during release readiness reviews, add a directive to your DevOps Agent Instructions (Agent.md), which is loaded in full at the start of every session:

“When performing release readiness reviews, always load and apply the high-risk-feature-flag-recommendations skill to evaluate code changes for risk and recommend LaunchDarkly feature flags where appropriate.”

This guarantees the agent loads and applies the Skill for every release readiness review rather than relying on relevance detection to surface it.

Getting Started

To begin using feature flag orchestration with AWS DevOps Agent and LaunchDarkly:

  1. Enable AWS DevOps Agent in your AWS account to start building Skills and connecting MCP servers
  2. Set up the LaunchDarkly MCP server: Follow the LaunchDarkly MCP server documentation for installation and configuration instructions.
  3. Read the companion post: LaunchDarkly’s blog post explores why feature flags are essential infrastructure for SRE agents and how the LaunchDarkly MCP Server connects to AWS DevOps Agent for pre-deployment review and incident response workflows.

Conclusion

Feature flag orchestration with AWS DevOps Agent and LaunchDarkly reduces the manual coordination required during both deployment review and incident response. A DevOps Agent Skill surfaces flag recommendations before high-risk changes ship, and during incidents, the agent queries LaunchDarkly to recommend flag-based containment, providing faster resolution with less disruption than full rollbacks.

For developers using Kiro IDE, the same LaunchDarkly MCP server enables flag-aware code generation during development, shifting flag coverage left to the point of authorship. Together, these workflows provide layered coverage: individual developers build with flags, DevOps Agent’s release management capabilities validate coverage at deployment time, and DevOps Agent uses flag state during incident response.

Authors

Greg Eppel

Greg Eppel is a Principal Specialist for DevOps Agent and has spent the last several years focused on Cloud Operations and helping AWS customers on their cloud journey.

Carl Caum

Carl Caum is a Senior Product Manager for DevOps Agent focused on accelerating safe software delivery through agentic solutions.

Supercharge your cloud operations with the Kiro power for AWS DevOps Agent

Post Syndicated from Shashiraj Jeripotula original https://aws.amazon.com/blogs/devops/supercharge-your-cloud-operations-with-the-kiro-power-for-aws-devops-agent/

When an alarm fires at 2 AM, the first thing most engineers do is grep logs, check recent deployments, and trace code paths. However, the context they need — metrics, traces, topology, configurations — lives in a separate browser tabs and applications. What if your IDE could bring that cloud intelligence directly to your code, understand the full picture, and help you fix the issue end-to-end? Introducing, The Kiro power for AWS DevOps Agent removes that context switching by connecting your IDE directly to the AWS DevOps Agent, so you can investigate incidents, identify root causes, and generate fixes, all from the same place you write code.

This post is for developers and operators who develop applications using Kiro and want to troubleshoot production issues faster without leaving their editor. We’ll walk through how the power works, what it can do, and a step-by-step example of resolving a real incident.

The Kiro power for AWS DevOps Agent connects Kiro, the AI-powered IDE from Amazon, to the AWS DevOps Agent. It brings the production intelligence and release management in AWS DevOps Agent directly into your development environment — where you already plan, architect, debug, and ship code.

With this power installed, you can review your changes for production risks, investigate production incidents, optimize costs, review architecture, map service topology, and generate remediation code — all through natural language conversation, enhanced with the local context of your workspace.

Challenges in cloud operations today

Operating modern cloud applications means navigating a maze of interconnected services. A single user-facing error might require tracing through Amazon Elastic Container Service (Amazon ECS) tasks, Application Load Balancers, AWS Lambda functions, Amazon DynamoDB tables, and dozens of Amazon CloudWatch metric dimensions. Operators face persistent challenges:

  • Context switching — Investigating an incident requires jumping between the IDE, the AWS Management Console, log viewers, trace explorers, and documentation. Each switch costs time and breaks concentration during high-pressure incidents.
  • Siloed knowledge — Understanding which metrics matter, which services depend on each other, and what “normal” looks like for a given application often lives in runbooks that are outdated or in the heads of senior engineers. New team members face a steep learning curve.
  • Remediation gap — Even after identifying a root cause, translating findings into a working fix — an AWS CloudFormation parameter change, a scaling policy update, or an AWS Identity and Access Management (IAM) policy correction — requires switching contexts again and manually applying changes.
    These challenges compound when teams operate across multiple AWS accounts and environments. Kiro powers address these challenges by bringing operational intelligence directly into the IDE where developers already work.

Challenges in modern software delivery

AI coding agents have changed how fast code gets written, but the code review, testing, and pipeline processes that move code to production were designed for human pace and haven’t kept up. Teams face two persistent challenges:

  • Review capacity — AI-assisted development produces changes faster than human reviewers can evaluate them. Changes that don’t adhere to internal standards, dependency breaks, and access-control gaps that would have been caught by human reviews can slip through at machine pace.
  • Invisible dependencies — Applications span multiple repositories, shared infrastructure, and cross-team API contracts. A parameter rename in one repository silently breaks downstream consumers, and no single reviewer holds the full dependency graph in their head.

Faster code generation without corresponding delivery automation simply moves the bottleneck downstream. The Kiro power for AWS DevOps Agent addresses this by bringing release management intelligence into the IDE so you can review changes for production risks and run exploratory release testing of your web and API applications. Any issues can be immediately mitigated before you even push your code changes.

What are Kiro powers?

A Kiro power is a curated package that gives Kiro specialized capabilities in a specific domain, in this case, AWS operations. When installed, the power provides Kiro with tool connections to your AWS environment, domain-specific knowledge (best practices, error recovery patterns), and instructions for routing your requests to the right workflow. Critically, the power combines your local workspace context (code, git history, configuration files) with cloud-side intelligence (metrics, topology, deployment history) — so Kiro understands both what your code does and how your infrastructure behaves. For a deeper look at the powers framework, see Getting started with Kiro powers

Each power typically includes:

  • MCP server configuration — Connects Kiro to external tools and data through the Model Context Protocol, providing read and write access to cloud resources
  • Steering files — Domain-specific instructions that teach Kiro how to route intents, choose the right workflow, and handle edge cases
  • Contextual knowledge — Domain-specific guidance captured in markdown spec files and lifecycle hooks that encode best practices, common patterns, and error recovery strategies (as described in the blog, Introducing powers).

The Kiro power for AWS DevOps Agent

The Kiro power for AWS DevOps Agent packages the full capabilities of AWS DevOps Agent into a single install for Kiro. Once enabled, Kiro gains the ability to converse with a specialized AI agent that has deep knowledge of your AWS infrastructure, your operational history, and AWS best practices.

You can do the following with this power:

  • Investigate incidents — Describe the symptoms in natural language (“ECS tasks are failing with OOM errors on my-service”) and Kiro orchestrates a deep investigation across CloudWatch metrics, AWS X-Ray traces, Amazon ECS task events, and recent deployments to identify the root cause.
  • Optimize costs — Ask “What cost savings are available for my ECS services?” and receive specific, data-backed recommendations with estimated monthly savings based on actual utilization metrics from your account.
  • Review architecture — Request a topology map or security audit of your services. The agent queries your infrastructure and returns findings with actionable improvement suggestions.
  • Chat across agent spaces — Operate across multiple AWS DevOps Agent agent spaces from a single Kiro session using AWS SigV4. Each agent space can represent a different team, application, or AWS account — and you can switch between them naturally.
  • Generate remediation code — After identifying a root cause, Kiro can generate the fix directly in your workspace. Because it has access to both the investigation findings and your local code, the remediation is specific to your application, not generic boilerplate.
  • Run a release readiness review — After finishing a batch of code changes, have the DevOps Agent review the changes for dependency risks, deviations from your standards and best practices, and expansion of access controls in CloudFormation that go beyond best practices. It also builds and runs your code in an AWS-managed sandbox to better assess any production risks.
  • Perform exploratory release testing for deployed applications — If you deploy your web or API application to a production-like environment, Kiro can have the DevOps Agent run an exploratory tests on it. Any bugs or regressions found can be fixed without leaving the IDE.

How it works

The power provides two complementary workflows that Kiro selects automatically based on your request:

  • Chat (updates in seconds) — For instant answers about cost, architecture, topology, and knowledge discovery. Kiro creates a conversation with the DevOps Agent and streams responses in real time. Follow-up questions retain full context within the same session.
  • Investigation (completes in minutes) — For complex incidents requiring deep analysis. The DevOps Agent examines CloudWatch metrics, X-Ray traces, deployment history, and service topology, then delivers a root cause analysis with prioritized recommendations.

The following diagram shows how Kiro combines local workspace context with the DevOps Agent’s cloud intelligence:

Kiro combines local workspace context with the DevOps Agent's cloud intelligence through the AWS DevOps Agent MCP Server.

Figure 1: Kiro combines local workspace context with the DevOps Agent’s cloud intelligence through the AWS DevOps Agent MCP Server.

Prerequisites

Before using the power, ensure you have:

  1. AWS credentials configured (AWS IAM Identity Center recommended) if using AWS SigV4.
  2. Kiro installed and a workspace set up
  3. An AWS DevOps Agent agent space configured with data sources (CloudWatch, X-Ray, or other integrations)
  4. Create an access token or have AWS SigV4 configured. The access tokens feature must be enabled on your Agent Space for access tokens to work.
  5. For access tokens, you must have IAM permissions to manage access tokens (aidevops:CreateAccessToken, aidevops:RevokeAccessToken, aidevops:RotateAccessToken).
    • Enable access tokens
      • Review the security best practices detailed in the connect to DevOps Agent Remote Server documentation.
      • Sign in to the AWS Management Console and open the AWS DevOps Agent console.
      • Choose your Agent Space.
      • Choose the Configuration tab.
      • In the Access tokens section, choose Enable.
      • Confirm the action.
    • Create a token
      • Open the DevOps Agent web app for your Agent Space, then from the navigation menu, choose Settings, then choose Access Tokens.
      • Choose Create access token.
      • Enter a name for the token.
      • Choose a scope:
      • read – View investigations, recommendations, chats, and Agent Space resources.
      • operate – Full access. Includes everything in read, plus send messages, create chats, and manage backlog tasks and recommendations.
      • Set an expiration (1 to 60 days).
      • Copy the token value and store it in a safe, secure location. You cannot retrieve it again.
      • After creating a token, the web app displays a configuration example that you can copy directly into your client.

The power works with any agent space that has active data sources. The more data sources connected, the richer the investigations and recommendations.

Getting started with the Kiro power for AWS DevOps Agent

Setting up the power takes only a few steps. You can install it directly or follow these steps:

  1. Open Kiro and choose the Powers icon in the sidebar.
  2. In the AVAILABLE panel, find AWS DevOps Agent.
  3. Choose Install.
  4. The power appears in the INSTALLED panel, and choose Try power.
Kiro powers panel showing the Kiro power for AWS DevOps Agent

Figure 2: Kiro powers panel showing the Kiro power for AWS DevOps Agent

Verify Installation

After installation, you should see the Kiro power for AWS DevOps Agent listed in the powers section of the Kiro panel. Navigate to mcp.json file and change these values accordingly, and save the config file.

  • DEVOPS_AGENT_TOKEN=<your-token>
  • DEVOPS_AGENT_REGION=<your-agent-space-region>

In the MCP Servers panel, you will see DevOps Agent MCP connected and also displays list of tools. The power activates automatically when you mention relevant keywords like incident, cost optimization, architecture review, or topology in your conversation.

Figure 3: MCP Servers panel showing the AWS DevOps Agent MCP and connected tools

Figure 3: MCP Servers panel showing the AWS DevOps Agent MCP and connected tools

Walkthrough: Investigating a production incident

Let’s walk through a realistic scenario. Your team receives a CloudWatch alarm: an Amazon ECS service is returning HTTP 503 errors and task restarts have spiked.

Step 1: Describe the problem

In Kiro, you type:

“My ECS service checkout-api is throwing 503 errors. The alarm fired 10 minutes ago. Here’s the error from my logs: Connection pool exhausted, max connections 50 reached.”

Because Kiro has access to your workspace, it automatically includes relevant context — your task definition, your connection pool configuration from application.yml, and your recent git commits.

Step 2: Kiro starts the investigation

Kiro routes this to the investigation workflow. You see real-time progress as findings stream in:

  • Planning investigation approach…
  • Querying CloudWatch metrics, ECS task events, X-Ray traces…
  • Analyzing connection pool metrics against task count…
  • Root cause identified: Connection pool sized for single task, but service scaled to 5 tasks sharing a database connection limit

Step 3: Review findings and recommendations

The DevOps Agent returns a detailed analysis:

Root cause: The database connection limit (50) is shared across all ECS tasks. When the auto-scaling policy added tasks at 08:47 UTC, each task attempted to open 50 connections, exceeding the Amazon RDS max_connections parameter (100).

Recommendation and Mitigation: Reduce the per-task connection pool to max_connections / max_tasks (100 / 5 = 20 per task), or increase the RDS instance class to support more connections.

Step 4: Generate and apply the fix

You ask Kiro to implement the recommendation. Because it has access to your application.yml and your AWS CloudFormation template, it generates a targeted fix:

  • Updates spring.datasource.service.maximum-pool-size from 50 to 20 in your application configuration
  • Adds a comment explaining the calculation
  • Suggests an RDS parameter group change if you want to increase capacity instead

The fix is applied directly in your workspace, ready for review and commit.

Operating across multiple agent spaces

If your team manages multiple applications, each with its own DevOps Agent agent space, you can switch between them naturally. Kiro lists available agent spaces and routes your question to the right one.

Conclusion

The Kiro power for AWS DevOps Agent brings the full operational intelligence of AWS DevOps Agent into the IDE where you already work. By combining your local workspace context with cloud-side analysis, it closes the loop from detection to remediation without context switching.

Whether you are triaging a production incident, optimizing costs across services, or onboarding a new team member who needs to understand your infrastructure, the power provides contextual answers grounded in your actual AWS environment.

Install the Kiro power for AWS DevOps Agent today and experience AI-powered cloud operations in your IDE. To learn more, visit the Interfacing with AWS DevOps Agent and the Kiro powers documentation.

Tipu Qureshi Tipu Qureshi
Tipu Qureshi is a Senior Principal Technologist in AWS Agentic AI, focusing on operational excellence and incident response automation. He works with AWS customers to design resilient, observable cloud applications and autonomous operational systems.
Shashiraj Jeripotula (Raj) Shashiraj Jeripotula (Raj)
Shashiraj Jeripotula (Raj) is a San Francisco-based Principal Partner Solutions Architect at AWS. He works with ISV and AWS partners to build deep integrations across observability, AI, and agentic development tooling — helping developers leverage AI agents, Model Context Protocol (MCP), and shift-left observability to build responsible, production-ready AI systems on AWS.


AWS DevOps Agent adds release management capabilities to assess code changes before production (preview)

Post Syndicated from Esra Kayabali original https://aws.amazon.com/blogs/aws/aws-devops-agent-adds-release-management-capabilities-to-assess-code-changes-before-production-preview/

Today, we’re announcing a new release management capability in AWS DevOps Agent that is now available in preview. AWS DevOps Agent is your always-available teammate that spans software changes and operations across AWS, multicloud, and on-premises environments. The practice of DevOps aims to make software change and operations smooth and increasingly autonomous, and AWS DevOps Agent delivers on both by leveraging its deep understanding of your environment, your services, their dependencies, and how they behave in production. Already generally available for post-deployment operations, it autonomously investigates incidents, provides root cause analysis and mitigation steps, and delivers targeted recommendations to prevent recurring issues. With today’s preview, AWS DevOps Agent adds release readiness review of code changes and autonomous release testing. These new features verify every change against the natural language standards you give to the DevOps Agent and run change-specific tests in production-like environments. AWS DevOps Agent now supports teams from code creation to production, helping reviewers and testers keep pace with the volume of AI-generated code.

As development teams adopt AI coding tools, the volume of pull requests moving through delivery pipelines has increased faster than review and testing processes can handle. When teams are under pressure to keep up, reviews are approved without thorough examination, and test environments drift from production. The value that coding agents generate sits waiting in review queues instead of reaching end users. At the same time, AI models are increasingly capable of catching functional and security issues that human reviewers might miss under time pressure, making speedy and safe delivery a requirement rather than a tradeoff.

The release readiness review feature evaluates every code change against production requirements, dependency safety, and the standards and best practices you provide to the DevOps Agent. The agent checks cross-repository dependency risks that could affect other services, access control changes against AWS Well-Architected Framework best practices, and compliance with any standards you have defined. When no standards are provided, the agent applies general best practices. As part of the review, the agent also runs your software in an AWS-managed isolated environment, executing lightweight user journey tests to verify the software builds, runs, and passes basic functional checks before the change enters the pipeline. Findings appear in the AWS DevOps Agent console and as comments on pull requests in GitHub or GitLab. You can also invoke reviews directly from your IDE through the Kiro power or Claude Code plugin, so developers can identify and fix dependency risks, standards violations, and access control issues before the change is committed to version control.

The autonomous release testing feature goes further, generating and running change-specific test plans for web and API-based applications in customer-provisioned, production-like environments before the change merges. Rather than running a static test suite, the agent reasons about what the change does and constructs tests tailored to it, covering functional correctness, behavioral regressions, and integration scenarios that a manually maintained test plan might not anticipate. Every test run produces structured artifacts including metrics, logs, traces, and an execution summary, giving reviewers a consistent record of what was tested and what the results were.

Getting started with AWS DevOps Agent release management
This walkthrough shows how to run an on-demand release readiness review using the AWS DevOps Agent web app. Before you begin, confirm that you have at least one GitHub or GitLab repository connected to your Agent Space. Once your repositories are connected, AWS DevOps Agent will index your code and build a knowledge graph of cross-repository and cloud dependencies.

To open the web app, navigate to the AWS DevOps Agent console, select your Agent Space, and choose the Web app tab. Choose Operator access to open the web app.

Without standards configured, the agent applies general best practices. To tailor reviews to your internal standards, navigate to Knowledge, then choose the Instructions tab. You will see a list of instruction sets, each scoped to a specific agent or task. Choose View next to Release readiness review to edit the instructions for production-readiness change review. Write your internal standards in plain English. For example, you can define infrastructure and data standards on encryption or network access rules, best practices that warn without blocking such as logging and observability requirements, and sensitive data classification best practices that identify applications or resources requiring higher security measures. To apply instructions across all agents in your space, choose View next to All agents.

You can trigger a release readiness review in two ways: by submitting a pull request to a connected repository, or by entering an on-demand query in the chat interface. To run an on-demand review from chat, choose New chat and enter a request such as:

Perform a production risk analysis on my repository branch

The agent will ask for the repository and branch you want to analyze. You can provide a branch name, a pull request number, or a commit SHA. Once you confirm your selection, the agent queues the review and analyzes the change for production risks, including infrastructure impacts, configuration changes, and potential issues.

After the review completes, you can ask follow-up questions directly in the chat to explore the findings in more detail. For example, you can ask which downstream consumers a change affects, and the agent will return a structured breakdown of in-repository and cross-repository consumers that will break, the specific files and line numbers affected, and the recommended steps to resolve the issue before deployment.

After submitting a review request, navigate to Changes in the left navigation pane. The Proposed changes table shows each review that has run, including the proposed change description, its source, category, status, and when it was created. You can filter by category or status to find specific reviews, or search by name using the search bar. Choose any entry to open the full execution detail.

The Timeline tab shows the agent’s step-by-step reasoning process, including the tools it called, the dependencies it consulted, and the observations it made at each step. Each entry is timestamped, giving you a complete record of how the agent built its understanding of the change and reached its conclusion.

Choose the Report tab to see the final recommendation. The report opens with a summary header showing the recommended action, the number of critical issues found, the commit revision, and the number of files changed. The recommended action is either BLOCKProceed with Caution, or Safe to Release.

Below the summary header, the Analysis section explains why the recommendation was made, citing specific risks and the evidence the agent found to support its conclusion. The Issues section lists each finding by severity, giving you a prioritized view of what needs to be addressed before the change can proceed. The Recommendations section provides specific, actionable steps the developer can take to resolve each issue. Finally, the Changes section lists each file that was modified, with the type of change, the category it falls under, and a description of what was changed, so reviewers have a complete picture of what the change does before it merges.

You can also invoke the autonomous release testing feature directly from the chat interface. To run an autonomous release test on a web or API-based application, choose New chat and enter a query such as:

Run a release test on my application deployed at [application URL]

The agent generates a change-specific test plan and executes it in your provisioned environment. Results appear in Changes, where you can review the execution steps and a structured summary of what was tested.

Get started today
The release readiness review and autonomous release testing features for AWS DevOps Agent are available in preview. These features are available at no additional cost during preview in the US East (N. Virginia) Region. For pricing information on other AWS DevOps Agent features, visit the AWS DevOps Agent pricing page.

For configuration details, visit the AWS DevOps Agent user guide.

— Esra

Accelerate Incident Resolution with PagerDuty and AWS DevOps Agent

Post Syndicated from Shan Kandaswamy original https://aws.amazon.com/blogs/devops/accelerate-incident-resolution-with-pagerduty-and-aws-devops-agent/

When something breaks in production, you find out fast. Understanding why it broke, before the damage spreads, is the hard part. That is where Site Reliability Engineering (SRE) teams lose the most time.

Think about the last time you got paged at 2 a.m. The alert said something broke, not why. You open four or five dashboards, cross-reference deployment logs with AWS CloudTrail events, and scroll through metrics. Twenty or thirty minutes burn before the picture comes together. That manual correlation is where resolution time balloons.

What if the investigation started before you opened your first dashboard?

That’s the idea behind connecting the new native PagerDuty Capability Provider in AWS DevOps Agent. The two systems now talk directly over a built-in OAuth 2.0 connection. When a PagerDuty incident triggers, the DevOps Agent starts investigating while responders are still getting oriented. Connecting them takes a few fields in a console.

What AWS DevOps Agent does

AWS DevOps Agent is a frontier agent built to help engineering teams investigate and resolve production incidents faster. The DevOps Agent works as a first responder, conducting federated investigations across your observability stack, tracing incidents from code changes all the way through to cloud infrastructure impact, and producing detailed mitigation plans. Beyond reactive investigations, it also proactively recommends improvements to your observability, infrastructure, and deployment pipelines to help prevent recurring issues. Through the AWS DevOps Agent web app, you can observe investigations as they unfold, access findings, and steer the analysis in real time.

The central concept is the Agent Space. Think of it as the boundary that defines what your agent can access. Your AWS account serves as the primary source, and from there you layer on secondary capabilities from telemetry providers like Datadog, Dynatrace, New Relic, or Splunk; pipeline tools like GitHub and GitLab; communications from PagerDuty and Slack; and custom Model Context Protocol (MCP) servers for anything else. Every investigation the agent runs, it learns. It maps relationships between your resources such as load balancers to services, services to databases, and deployments to config changes. One team we’ve worked with had the agent map hundreds of infrastructure relationships, and that number keeps growing with each investigation it completes.

PagerDuty, of course, needs no introduction to anyone who’s been responsible for resolving critical, customer-impacting incidents. Engineering teams rely on it to detect, triage, resolve, and learn from incidents. The native PagerDuty Capability Provider in AWS DevOps Agent connects the two directly. PagerDuty incident events drive AWS DevOps Agent investigations automatically. Findings flow back to the originating PagerDuty incident record, including root cause analysis and recommended mitigation steps. They are also available in the AWS DevOps Agent console and web app, giving your whole team visibility into what the agent discovered.

There’s a second piece to this integration worth understanding. By adding the PagerDuty MCP Server as a capability and configuring an AWS DevOps Agent skill for working with PagerDuty, you enable AWS DevOps Agent to query PagerDuty’s institutional memory during investigations. This includes past incidents, diagnostics, resolution patterns, and operational context across both AWS and non-AWS environments. This PagerDuty MCP Server-based connection is separate from the Capability Provider event flow and requires its own setup (covered in Step 6 below). The result is investigations informed by both current signals and prior incident history.

Why this matters

These are practical, tangible changes for your team:

Faster time to root cause. When a PagerDuty incident triggers, AWS DevOps Agent kicks off an investigation automatically. No one has to sign in to another tool, step through a wizard, or remember to initiate anything. The investigation is already running by the time you acknowledge your alert.

Real contextual analysis. The agent correlates PagerDuty incident data with Amazon CloudWatch metrics, AWS CloudTrail logs, application topology, and deployment history, plus telemetry from whichever third-party observability providers you’ve connected, like Datadog, Splunk, New Relic, or Dynatrace. It connects dots that would otherwise take humans significant time to even start connecting.

Investigations start when an incident triggers. AWS DevOps Agent automatically conducts the deep-dive investigation behind the scenes. It reports back its root cause analysis and proposed mitigation steps into the originating PagerDuty incident, with a link to the AWS DevOps Agent web app for more details.

Less time playing detective, more time fixing things. That manual data correlation across four or five tools? The agent handles it. Your people can focus on actually resolving the issue instead of building the investigation timeline by hand.

Nothing extra to host. The native PagerDuty Capability Provider means you’re not standing up additional infrastructure. No servers to manage, no endpoints to maintain on your side.

How the integration works

The architecture is straightforward. Here’s the flow:

High-level architecture diagram showing PagerDuty connected to AWS DevOps Agent through a native OAuth 2.0 Capability Provider, with the agent investigating across AWS CloudWatch, AWS CloudTrail, and connected telemetry and pipeline tools

Figure 1: High-level architecture, native PagerDuty Capability Provider in AWS DevOps Agent.

AWS DevOps Agent and PagerDuty authenticate to each other using OAuth 2.0 Scoped OAuth. You register PagerDuty once at the AWS account level as a Capability Provider, and then add it to whichever Agent Spaces need it. Registration is shared across Agent Spaces in the account, so you don’t have to repeat the setup per team.

Once a PagerDuty incident triggers, AWS DevOps Agent picks up the event over the native connection and begins investigating:

  1. Receives the PagerDuty incident event (service, severity, and initial context) via the native Capability Provider connection
  2. If the PagerDuty MCP capability and AWS DevOps Agent skill are configured, queries PagerDuty for related historical incidents, past diagnostics, and resolution patterns to enrich the investigation
  3. Examines AWS resource topology and the relationships between your infrastructure components through its knowledge graph
  4. Reviews AWS CloudTrail logs for recent changes or anything that looks off
  5. Queries Amazon CloudWatch and connected telemetry providers (Datadog, Dynatrace, New Relic, Splunk) for relevant metrics and traces
  6. Cross-references deployment events from configured pipeline tools (GitHub, GitLab) against the incident timeline
  7. Synthesizes potential root causes from all the evidence it’s gathered

The agent builds up a comprehensive picture by introspecting AWS observability data, pulling from connected capability providers, and leveraging the topology mapping that creates a knowledge graph of your application infrastructure. Every investigation it runs expands its understanding of how your resources connect. It discovers relationships you might not have explicitly documented, building a richer map with each incident it works.

Beyond raw data, the agent produces detailed mitigation plans with specific actions to resolve the issue, validate the fix, and revert if needed. The agent posts its findings, root cause summary, and recommended next steps directly to the originating PagerDuty incident record, giving your on-call team actionable information without them having to go digging.

A quick note on security, because it matters. The native connection uses OAuth 2.0 Scoped OAuth with a minimum set of PagerDuty scopes (incidents.read incidents.write services.read webhook_subscriptions.read webhook_subscriptions.write). AWS DevOps Agent only supports the newer scoped OAuth flow; legacy PagerDuty OAuth with a redirect URI is not supported. For inbound events from PagerDuty, only V3 webhooks are supported. Earlier webhook versions won’t work. Traffic flows over HTTPS.

Getting it set up

Setup comes in four phases: register PagerDuty as a Capability Provider at the account level, attach it to your Agent Space, configure the PagerDuty MCP server and AWS DevOps Agent skill for working with PagerDuty to enrich investigations, and verify things work end to end.

What you’ll need

  • An active AWS account with permissions to use AWS DevOps Agent
  • AWS DevOps Agent enabled in a supported AWS Region. You’ll create an Agent Space, which needs two AWS Identity and Access Management (IAM) roles (one for Agent Space operations, one for web app functionality). Both can be auto-created during setup
  • A PagerDuty account with permission to register OAuth apps, plus an Administrator role for Events Integration
  • A PagerDuty Advance license and a PagerDuty User API token (for the MCP integration in Step 6)
  • Your PagerDuty account subdomain (so if your PagerDuty URL is https://your-company.pagerduty.com, the subdomain is your-company)
  • An OAuth client ID and client secret from a PagerDuty app registered with OAuth 2.0 Scoped OAuth

Step 1: Create your Agent Space

Stand up an Agent Space in the AWS DevOps Agent console. This defines the boundary for what the agent can reach into and investigate.

  1. Head to the AWS DevOps Agent console home page.
AWS DevOps Agent console home page with a Begin setup call to action to create your first Agent Space

AWS DevOps Agent console home page.

  1. Create a new Agent Space with a name and a short description, usually scoped to a service or application team’s responsibilities
Create Agent Space form with fields for Agent Space name, optional description, and agent response language

Creating a new Agent Space with a name and description.

  1. Create the Agent Space IAM roles (AWS DevOps Agent requires two IAM roles: one for Agent Space operations and another for its associated web app functionality). You can auto-create them during setup
Agent Space setup screen showing the two IAM roles required, one for Agent Space operations and one for web app functionality

Configuring the two IAM roles required for the Agent Space.

Detailed view of IAM role auto-creation options during Agent Space setup

IAM roles can be auto-created during setup.

  1. Your primary source (the AWS account you’re creating the Agent Space in) is added automatically. If you need the agent to investigate resources in other accounts, add those as secondary sources
Agent Space sources screen showing the AWS account added automatically as the primary source

The AWS account is added automatically as the primary source.

Step 2: Add supporting capabilities

Out of the box, the agent connects to Amazon CloudWatch for metrics, logs, and alarms, and can investigate AWS CloudTrail API activity and AWS X-Ray traces through its read-only permissions. That said, most teams don’t live entirely inside AWS tooling, and that’s where third-party capability providers pull their weight. You can wire in external tools to give the agent a fuller picture of your world:

  • Telemetry: Datadog, Dynatrace, New Relic, or Splunk, so the agent can pull metrics and traces beyond Amazon CloudWatch during investigations
  • Pipelines: GitHub or GitLab, so it can correlate deployments and code changes with incidents
  • Communications: Slack, for team coordination and investigation updates (PagerDuty is configured separately as a Capability Provider in Step 4)
  • MCP Servers: Custom integrations via OAuth or API keys for anything else in your stack

You don’t need everything connected on day one. Start with what makes sense and add more as you go. Each new capability helps the agent discover more infrastructure relationships and investigate more effectively.

Step 3: Set up application topology

Help the agent understand what your application landscape looks like:

  1. Configure IAM roles to define the AWS topology scope for your Agent Space. The agent uses these permissions to determine which resources it can see and investigate
  2. Give the agent time to discover and map the relationships between your resources (it does this automatically as it runs investigations)
  3. Check the interactive topology visualization in the console and make sure your critical components are showing up correctly
  4. If you want the agent to focus on certain tags or resource subsets, add those instructions to your skills

Step 4: Register PagerDuty as a Capability Provider

You register PagerDuty once at the AWS account level. From there, it’s shared across every Agent Space in the account.

First, create the OAuth app in PagerDuty:

  1. In a separate browser tab, sign in to PagerDuty and go to Integrations > App Registration
PagerDuty Integrations menu showing the App Registration option

In PagerDuty, navigate to Integrations then App Registration.

PagerDuty App Registration page for creating a new app

PagerDuty App Registration page.

  1. Create a new app using OAuth 2.0 Scoped OAuth. AWS DevOps Agent does not support legacy PagerDuty OAuth with redirect URI
PagerDuty new app form with OAuth 2.0 Scoped OAuth selected as the authentication type

Create the app using OAuth 2.0 Scoped OAuth.

  1. Under Permissions, grant the minimum scopes: incidents.read incidents.write services.read webhook_subscriptions.read webhook_subscriptions.write
PagerDuty OAuth permissions screen showing the minimum required scopes for incidents, services, and webhook subscriptions

Granting the minimum required OAuth scopes.

  1. Turn on Events Integration so AWS DevOps Agent and PagerDuty can talk in both directions
PagerDuty app configuration with Events Integration enabled

Turn on Events Integration for two-way communication.

  1. Copy your Client ID and Client Secret. You’ll paste them into the AWS console in a minute
PagerDuty app credentials screen displaying the Client ID and Client Secret

Copy the Client ID and Client Secret from PagerDuty.

Then, register PagerDuty in the AWS DevOps Agent console:

  1. In the AWS DevOps Agent console, open the Capability Providers page from the side navigation
  2. In the Available providers section, find PagerDuty under Communication and choose Register
AWS DevOps Agent Capability Providers page with PagerDuty listed under Communication and a Register button

Find PagerDuty under Communication and choose Register.

  1. On the Configure access in PagerDuty page, pick your PagerDuty region (US or EU) and enter your PagerDuty subdomain (if your PagerDuty URL is https://your-company.pagerduty.com, the subdomain is your-company)
  2. Paste in the OAuth Client name, Client ID, and Client secret from PagerDuty. Confirm the minimum scopes (incidents.read incidents.write services.read webhook_subscriptions.read webhook_subscriptions.write)
Configure access in PagerDuty form with fields for region, subdomain, OAuth client name, client ID, and client secret

Enter your PagerDuty region, subdomain, and OAuth credentials.

  1. Review the configuration and choose Add
Review screen for the PagerDuty Capability Provider configuration before adding

Review the configuration and choose Add.

Once registration goes through, PagerDuty shows up under the Currently registered section of the Capability Providers page.

Capability Providers page showing PagerDuty under the Currently registered section

PagerDuty appears under Currently registered after registration.

Step 5: Add PagerDuty to your Agent Space

PagerDuty is registered at the account level. Now connect it to the Agent Space that needs it:

  1. In the AWS DevOps Agent console, pick your Agent Space
  2. Open the Capabilities tab
  3. In the Communications section, choose Add
Agent Space Capabilities tab with the Add button in the Communications section

On the Capabilities tab, choose Add in the Communications section.

  1. Select PagerDuty from the list of available providers
Provider selection list with PagerDuty available to add to the Agent Space

Select PagerDuty from the list of available providers.

  1. Choose Associate service

To update OAuth credentials or remove PagerDuty from an Agent Space, see the AWS DevOps Agent documentation.

Step 6: Add PagerDuty MCP Server and configure the agent skill

The Capability Provider from the previous steps handles the event flow. When a PagerDuty incident triggers, AWS DevOps Agent investigates and posts findings back to the originating PagerDuty incident. To let the agent also pull context from PagerDuty during those investigations, you add two things: the PagerDuty MCP server as a custom MCP capability, and an AWS DevOps Agent skill for working with PagerDuty that tells the agent when and how to use it.

Prerequisites:

  • PagerDuty Advance license
  • A PagerDuty User API token (generate one at User Settings > API Access in PagerDuty)

Add the PagerDuty MCP server:

  1. In your Agent Space, go to Capabilities tab > MCP Servers
Agent Space Capabilities tab showing the MCP Servers section

Open the MCP Servers section on the Capabilities tab.

  1. Add a new custom MCP server with the following configuration:
    • Server URL: https://mcp.pagerduty.com/mcp
    • For EU region PagerDuty accounts, use https://mcp.eu.pagerduty.com/mcp instead
    • Authentication: PagerDuty User API token in the format Token token=<your-pagerduty-api-key>
Add custom MCP server form in the AWS DevOps Agent console

Add a new custom MCP server.

MCP server configuration showing the server URL field and PagerDuty User API token authentication field

Configure the server URL and PagerDuty User API token.

Add the AWS DevOps Agent skill for working with PagerDuty:

The MCP server gives the agent access to PagerDuty tools. The skill tells the agent when and how to use them during investigations.

  1. In your Agent Space, choose Operator access to open the web app in a separate browser window
Agent Space console with the Operator access option to open the web app

Choose Operator access to open the web app.

  1. In the Agent Space Operator web app, navigate to Knowledge and the Skills tab, then choose Add skill
AWS DevOps Agent Operator web app Skills page with the Add skill button

On the Skills page, choose Add skill.

  1. You can select Create skill to create a skill through a wizard, interactively chat with the agent to create a skill, or upload a skill zip file if you already have one
Create skill options showing wizard, interactive chat, and zip upload methods

Choose how to create the skill.

  1. Choose Create skill and fill out the skill instructions from the table below to create a skill
Skill creation form with fields for name, description, status, agent type, and instructions

Fill out the skill instructions.

  1. You should see the pagerduty-aws-devops-agent skill added to the AWS DevOps Agent
Skills page showing the pagerduty-aws-devops-agent skill successfully added and active alongside the core skills

The pagerduty-aws-devops-agent skill added to AWS DevOps Agent.

Skill form instructions:

Field Value
Name pagerduty-aws-devops-agent
Description Use this skill to interact with the PagerDuty Advance SRE Agent for incident response, troubleshooting, runbook generation, and log search. Invoke when the agent is investigating incidents, performing triage, root cause analysis, or resolving operational issues. This skill calls the sre_agent_tool from the pagerduty-advance-mcp MCP server to access PagerDuty’s historical incident data, diagnostics, and resolution patterns.
Status Active
Agent Type Generic
Instructions See the skill instructions code block below.

Skill instructions (paste into the Instructions field):

# PagerDuty Advance SRE Agent

Use the PagerDuty MCP Server to call the `sre_agent_tool` for incident response and technical troubleshooting.

## Prerequisites

This skill requires the `pagerduty-advance-mcp` MCP server to be configured in the Agent Space under Capabilities > MCP Servers.

1. Extract the PagerDuty incident ID from the investigation context
2. Call the `sre_agent_tool` from the `pagerduty-advance-mcp` MCP server with:
   - `message`: a natural language question about the incident
   - `incident_id`: the PagerDuty incident ID
3. If follow-up queries are needed, continue calling `sre_agent_tool` with the same `incident_id` and a new `message`. Pass the `session_id` from the previous response to maintain conversation

## Tool Details

- **Tool name:** `sre_agent_tool`
- **MCP Server:** `pagerduty-advance-mcp`
- **Parameters:**
  - `message` (string, required) — natural language question about the incident
  - `incident_id` (string, required) — the PagerDuty incident ID
  - `session_id` (string, optional) — reuse from previous response for conversation continuity

## What the SRE Agent Can Help With

- Active incident analysis, triage, and resolution
- Root cause analysis and technical explanations
- Incident summaries and catch-ups
- Status updates for stakeholders
- Diagnostic checks and remediation recommendations
- Log interpretation and troubleshooting guidance
- Alert trigger analysis and explanations
- Change event analysis and impact assessment
- Playbook and runbook generation
- Past incident correlation and pattern recognition
- Service dependencies and related system analysis
- Real-time incident monitoring and alerting questions

Step 7: Test and validate

Before you call it finished, confirm things work end to end:

  1. Create a test incident in PagerDuty
  2. Confirm AWS DevOps Agent picks up the event and starts an investigation
  3. Watch the investigation move along in the AWS DevOps Agent console or web app
  4. Review the root cause summary, the mitigation plan, and the investigation findings
  5. Verify that root cause analysis and mitigation steps appear on the originating PagerDuty incident record. If you’ve also connected Slack, check that updates land in your configured channel

Start with a limited scope for your initial Agent Space. Focus on a single application or service first. Get comfortable with the integration, tune your configuration, and then expand from there.

Troubleshooting

A handful of things we’ve seen trip people up:

Registration fails with invalid credentials. Double-check that the Client ID and Client secret were copied from the right PagerDuty OAuth 2.0 Scoped OAuth app. Legacy PagerDuty OAuth apps (the ones configured with a redirect URI) aren’t supported. When credentials do need to change, deregister from the Capability Providers page and re-register with the new values, rather than trying to edit in place.

Webhook events don’t trigger an investigation. AWS DevOps Agent only supports PagerDuty V3 webhooks. If your PagerDuty subscription is still on an older webhook version, upgrade to V3. Full details live in Webhooks Overview in the PagerDuty developer documentation.

PagerDuty shows as registered, but isn’t active in an Agent Space. Registering at the account level and adding the provider to an Agent Space are two separate actions. On the Agent Space’s Capabilities tab, check that PagerDuty appears under Communications. If it doesn’t, add it there.

Region or subdomain mismatch. If your PagerDuty account is on the EU service region, make sure you picked EU during registration. The subdomain has to match the first label of your PagerDuty URL exactly (for example, your-company from https://your-company.pagerduty.com).

Conclusion

Most of what happens in the first several minutes of incident response is undifferentiated heavy lifting like opening dashboards, tailing logs, correlating deployments with AWS CloudTrail events. With the native PagerDuty Capability Provider in AWS DevOps Agent, investigations automatically begin by the time you’ve acknowledged your alert, giving your engineers a head start on root cause analysis before responders have finished triaging.

To get started, check out the AWS DevOps Agent documentation or reach out to your PagerDuty or AWS account team.

Resources

About the authors

Shan Kandaswamy

Shan Kandaswamy

Shan is a Senior Partner Solutions Architect specializing in generative AI at AWS, dedicated to solving complex user challenges. He advocates for innovative AI solutions, distributed architecture, and serverless technologies, helping users harness the power of generative AI in their cloud journey. You can reach him on LinkedIn.

Laith Al-Saadoon

Laith Al-Saadoon

Laith Al-Saadoon is a Principal AI Engineer at AWS. He created and launched AWS MCP Servers (30M+ PyPI downloads) and contributes to Strands Agents SDK — AWS’s open-source framework for building AI agents — along with other agentic AI open-source projects like Mem0 and Agno. He drives AWS’s autonomous software development and agentic AI strategy and builds production agentic systems that make agents work for the world’s largest companies. In his personal time, Laith enjoys the outdoors — fishing, photography, drone flights, and hiking with his wife.

Scott Schreckengaust

Scott Schreckengaust

Scott Schreckengaust brings a biomedical engineering degree and decades of deep domain expertise in healthcare and life sciences to emerging technologies and AI. He’s spent his career building—from automating lab workflows and integrating enterprise systems to architecting full-stack software deployments in regulated environments. Now working as an AI engineer, Scott continues what he’s always done best: partner with customers to uncover their scientific and operational challenges, then engineer solutions that scale. His journey from the bench to the cloud reflects a consistent belief: the best technology is invisible—it just works.


Diagnose EKS Node Issues Faster with AWS DevOps Agent and Custom MCP

Post Syndicated from Shyam Kulkarni original https://aws.amazon.com/blogs/devops/diagnose-eks-node-issues-faster-with-aws-devops-agent-and-custom-mcp/

AWS DevOps Agent can investigate a growing range of production incidents autonomously. It diagnoses CrashLoopBackOff failures, traces ConfigMap deletions through audit logs, and correlates Amazon CloudWatch metrics with cluster events — all without human intervention.

But AWS DevOps Agent has a visibility boundary. When the data it needs lives outside its native integrations — on a node’s operating system, inside a third-party monitoring tool, behind a database’s internal diagnostics — the agent stalls. It can describe symptoms, but it can’t reach the evidence needed to identify root causes.

This post shows how to extend AWS DevOps Agent by building a custom Model Context Protocol (MCP) server that bridges that gap. Using a concrete example, we give AWS DevOps Agent structured access to Amazon EKS worker node diagnostics and explain how the same approach applies to data sources the agent can’t natively reach. By the end of this walkthrough, you will have a working MCP server that gives AWS DevOps Agent access to 20+ node-level log sources — providing autonomous investigation capabilities that can assist in root cause analysis compared to manual SSH sessions.

Prerequisites

Before you begin, make sure you have the following:

  • An Amazon EKS cluster with AWS Systems Manager Agent (SSM Agent) running on the worker nodes (included by default on Amazon EKS optimized AMIs)
  • Node.js v18 or later
  • AWS CLI v2
  • AWS CDK v2 installed and bootstrapped in your target account and Region
  • An AWS account with permissions to create IAM roles, Lambda functions, and Amazon S3 buckets
  • Familiarity with Amazon EKS, AWS Systems Manager, and the Model Context Protocol (MCP)

How AWS DevOps Agent discovers custom tools through MCP

MCP is an open standard that defines how AI agents discover and invoke external tools. AWS DevOps Agent supports connecting to custom MCP servers, which means you can expose new capabilities to it without modifying the agent itself. When you connect an MCP server to AWS DevOps Agent, the agent automatically discovers the available tools, understands their schemas, and calls them as part of its investigation workflow. You build and connect the MCP server — the agent handles the rest.

The extensibility model follows three steps: first, identify the data source that AWS DevOps Agent cannot natively access; second, build an MCP server that wraps safe, structured access to that data source; and third, connect the MCP server to AWS DevOps Agent so it can incorporate the new tools into its investigations.

Three design principles make this work. Return structured data, not raw text — pre-index findings with severity levels and stable IDs so the agent can filter, reference, and correlate them. Never give the agent a shell — mediate interactions through a controlled, auditable execution model. Make tools composable — design tool outputs to serve as inputs to other tools, creating a chain of evidence the agent can follow.

Why Amazon EKS node OS visibility matters

AWS DevOps Agent integrates with Amazon EKS to inspect pod status, read container logs, query CloudWatch Container Insights, and correlate cluster events. This covers application crashes, container-level resource exhaustion, and configuration drift.

However, EKS production issues with nodes originate in a layer these tools cannot reach: the node operating system. Artifacts such as iptables rules, full CNI configuration and IPAMD state, route tables, conntrack entries, dmesg kernel messages, containerd runtime logs, sysctl parameters, ENI metadata, and the unfiltered kubelet journal exist exclusively on the node. These artifacts are the primary evidence for diagnosing IP allocation failures, DNS resolution issues, network policy enforcement problems, storage mount timeouts, and node registration failures.

Integrating AWS DevOps Agent with an EKS node diagnostics MCP server

The sample-eks-node-diagnostics-mcp repository (sample-eks-node-diagnostics-mcp repository) demonstrates this pattern. It provides an MCP server that gives AWS DevOps Agent structured access to node-level diagnostic data, backed by AWS Systems Manager (SSM) Automation for safe, auditable execution.

How it works

AWS DevOps Agent connects over MCP/HTTPS to AgentCore Gateway, which authenticates via Amazon Cognito OAuth 2.0 and routes tool calls through a Lambda-based Tool Router to SSM Automation. SSM Automation dispatches runbooks to EKS worker nodes running SSM Agent, which upload collected log archives to a KMS-encrypted S3 bucket. An S3 event triggers a Lambda function that extracts and indexes findings for the agent to query.

Figure 1: End-to-end architecture of the EKS Node Diagnostics MCP server. AWS DevOps Agent discovers and invokes 19 tools through AgentCore Gateway, which dispatches SSM Automation runbooks to worker nodes for log collection and uploads results to Amazon S3 for extraction and indexing.

  1. AWS DevOps Agent calls a collect tool with an instance ID.
  2. The MCP server dispatches an SSM Automation execution to the target node, running the AWS-managed AWSSupport-CollectEKSInstanceLogs runbook.
  3. The runbook collects 20+ log sources — kubelet, containerd, iptables, CNI config, route tables, dmesg, sysctl, ENI metadata, IPAMD logs, and more — packages them into an archive, and uploads it to an Amazon S3 bucket where you configure AWS KMS encryption.
  4. A processing pipeline extracts the archive, pre-indexes errors with severity classification and stable finding IDs, and provides the results to you through additional MCP tools.

The server exposes tools for log collection, pre-indexed error retrieval, cross-file search and correlation, structured network diagnostics, and live packet capture. A typical agent workflow chains these together: collect → status → errors → search → correlate → read → summarize, with each step producing outputs that feed into the next.

AWS DevOps Agent does not get a shell on the node. Every interaction is mediated by SSM Automation — an auditable, IAM-controlled, non-interactive execution model.

Connecting through Amazon Bedrock AgentCore Gateway

The reference implementation uses Amazon Bedrock AgentCore Gateway to expose the Lambda-backed MCP server to AWS DevOps Agent. AgentCore Gateway converts Lambda functions into MCP-compatible tools and handles authentication, protocol translation, and tool discovery through a single managed endpoint.

The integration follows three steps:

Step 1: Create an OAuth authorizer with Amazon Cognito. The CDK stack provisions a Cognito User Pool configured for the OAuth 2.0 client credentials flow. This secures inbound access to the gateway — only clients with valid tokens can invoke tools.

Step 2: Create a gateway and register the Lambda as a target. Register the Lambda function that handles tool invocations as a target on the gateway. AgentCore Gateway automatically discovers the tool schemas from the Lambda and makes them available through the MCP protocol. The gateway endpoint becomes the single MCP URL for AWS DevOps Agent.

Step 3: Connect AWS DevOps Agent. Register the MCP server at the account level in the AWS DevOps Agent console, providing the gateway URL and OAuth configuration. Then allowlist the specific tools each Agent Space needs. AWS DevOps Agent authenticates by obtaining a JWT from the Cognito token endpoint using the client credentials grant and passes it as a Bearer token in requests to the gateway URL.

Deploying the MCP server

Deploy the entire stack using AWS CDK :

git clone https://github.com/aws-samples/sample-eks-node-diagnostics-mcp.git
 cd sample-eks-node-diagnostics-mcp
 chmod +x deploy.sh
 ./deploy.sh

The script walks you through cluster selection and node role configuration. Have the following ready before running the script: your target EKS cluster name, the IAM role ARN you attached to your worker nodes, and the AWS Region where your cluster runs. The script outputs your MCP gateway URL, OAuth credentials, and token endpoint — everything you need to configure the connection in AWS DevOps Agent. See the repository README for detailed deployment instructions, CI/CD mode, and prerequisite details.

Seeing it in action

To demonstrate the MCP server’s capabilities, we walk through a realistic node-level failure scenario on a test EKS cluster. We manually inject a fault that blocks pod DNS resolution at the iptables level — an issue that is invisible from kubectl since pods appear Running — then show how AWS DevOps Agent investigates and identifies the root cause using the MCP server’s tools.

Setting up the scenario

Start with an EKS cluster that has a managed node group with SSM Agent running (included by default on Amazon EKS optimized AMIs). Deploy a sample workload to one of the nodes:

kubectl create namespace demo-app

cat <<EOF | kubectl apply -f -
 apiVersion: apps/v1
 kind: Deployment
 metadata:
   name: web-frontend
   namespace: demo-app
 spec:
   replicas: 3
   selector:
     matchLabels:
       app: web-frontend
   template:
     metadata:
       labels:
         app: web-frontend
     spec:
       containers:
       - name: nginx
         image: nginx:latest
         ports:
         - containerPort: 80
 EOF

Identify the node and instance ID where the pods are running:

kubectl get pods -n demo-app -o wide

Injecting the fault

⚠ WARNING: The following commands will disrupt DNS resolution for all pods on the target node. Only run these in a non-production test environment. Do not execute on production nodes.

Connect to the target node using SSM Session Manager and run the following commands to block pod DNS traffic at the iptables level. This simulates a subtle networking issue – pods continue running but can’t resolve DNS, and the root cause is only visible in the node’s iptables rules:

# Block pod traffic to kube-dns ClusterIP — pods run but DNS fails
 # Only affects FORWARD chain (pod traffic), not the node's own DNS
 sudo iptables -I FORWARD -d 10.100.0.10/32 -p udp --dport 53 -j DROP
 sudo iptables -I FORWARD -d 10.100.0.10/32 -p tcp --dport 53 -j DROP

Replace 10.100.0.10 with your cluster’s kube-dns ClusterIP (kubectl get svc kube-dns -n kube-system -o jsonpath=’{.spec.clusterIP}’).

This fault is particularly insidious because kubectl get pods shows all pods in Running state. The applications fail with DNS resolution errors, but there is no Kubernetes event or pod status that points to the cause. The iptables DROP rules targeting the kube-dns ClusterIP exist only in the node’s firewall configuration — a layer that no Kubernetes API call can inspect.

Investigating with AWS DevOps Agent

An engineer notices applications reporting DNS failures and asks AWS DevOps Agent to investigate:

“Pods on node i-xxxxxxxxxx in cluster EKS-sample (us-east-1) are running but applications report DNS resolution failures. Collect the node logs and investigate.”

The AWS DevOps Agent "Start an investigation" dialog with the investigation details field populated: "Pods on node i-xxxxxxxxxxxx in cluster EKS-sample (us-east-1) are running but applications report DNS resolution failures. Collect the node logs and investigate." The date and time of incident is set to 2026-03-26T16:55:30.593Z.

Figure 2: Starting an investigation in AWS DevOps Agent. The engineer provides the symptom description and incident timestamp, and the agent autonomously plans and executes the investigation.

AWS DevOps Agent begins the investigation by recording the symptom and launching two parallel actions: collecting node logs via the nodelog_collect tool and checking cluster health. The cluster health check confirms all four nodes are running and SSM-online. The agent then polls the log collection status, tracking progress from 25% through 75% to completion. Once collection finishes, the agent fans out into parallel workstreams — running network diagnostics, performing quick triage, and collecting logs from a healthy node for comparison.

The investigation timeline progresses from "Starting" at 11:59:45 AM through symptom identification at +12 seconds, cluster health check at +33 seconds confirming all four nodes are running, log collection polling at 25% and 75%, to log collection complete at +1 minute 22 seconds. The agent then launches parallel network diagnostics, quick triage, and healthy node comparison.

Figure 3: Investigation timeline showing the initial data collection phase. The agent identifies the symptom, confirms cluster health, collects node logs via SSM Automation, polls for completion, and launches parallel diagnostic workstreams.

With the initial data collected, the agent launches four parallel investigation tasks to maximize coverage and minimize time-to-root-cause: (1) deep-dive-iptables-routes examines the node’s firewall rules and routing table in detail, completing in 1 minute 44 seconds across 8 tool calls; (2) search-network-errors scans the collected logs for network-related error patterns, running 15 tool calls over 7 minutes 51 seconds; (3) collect-healthy-node gathers the same diagnostics from a known-good node for comparison, taking 13 tool calls over 4 minutes 55 seconds; (4) check-oom-and-pod-status investigates kernel OOM kills and pod health, executing 19 tool calls over 8 minutes 12 seconds. Each task produces a structured report that feeds into the final synthesis.

Four parallel investigation tasks execute concurrently: deep-dive-iptables-routes (8 tool calls, 1 minute 44 seconds), search-network-errors (15 tool calls, 7 minutes 51 seconds), collect-healthy-node (13 tool calls, 4 minutes 5 seconds), and check-oom-and-pod-status (19 tool calls, 8 minutes 12 seconds). At +14 minutes 22 seconds, all four tasks complete and the agent begins synthesizing findings.

Figure 4: Parallel investigation phase. The agent runs four concurrent deep-dive tasks — iptables/route analysis, network error search, healthy node comparison, and OOM/pod status check — then synthesizes the findings into a unified report.

The iptables and route table deep-dive reveals the root cause. The agent identifies two CRITICAL findings: a FAULT-INJECT-DROP-POD-TO-POD rule in the FORWARD chain that drops inter-pod traffic, and a FAULT-INJECT-DROP-SERVICE-CIDR rule that drops forwarded traffic to the service CIDR range. It also flags a MEDIUM-severity finding — a blackhole route for 10.96.0.0/12 (the Kubernetes service CIDR) that does not exist on healthy nodes. The remaining checks come back normal: kube-proxy chains are intact, AWS VPC CNI SNAT/CONNMARK chains are properly configured, and the default gateway and ENI route tables are correct. This structured severity classification allows the agent to immediately focus on the critical items.

A severity-classified findings summary table from the deep-dive-iptables-routes task. Two CRITICAL findings: a FAULT-INJECT-DROP-POD-TO-POD rule and a FAULT-INJECT-DROP-SERVICE-CIDR rule, both in the FORWARD chain. One MEDIUM finding about limited pod /32 routes. Six Normal findings confirm kube-proxy chains, AWS VPC CNI SNAT/CONNMARK chains, FORWARD chain policy, per-ENI route table, and default gateway are all properly configured.

Figure 5: Deep-dive findings from the iptables and route table analysis. Two CRITICAL fault-injection DROP rules in the FORWARD chain are identified as the primary issue, while standard networking components — kube-proxy, VPC CNI, and routing — check normal.
The healthy node comparison confirms the diagnosis. The agent compares the unhealthy node against a known-good node across seven dimensions: security groups, ENI count, DNS configuration, iptables rules, route tables, conntrack entries, and IPAMD state. The key differences are definitive: the blackhole route for 10.96.0.0/12 exists only on the unhealthy node, kubelet API server timeout errors appear only on the unhealthy node, conntrack entries are 12x higher (1,962 vs 169), and IPAMD reconciliation errors are 5x more frequent. The iptables FORWARD chain counters show 2.4 billion packets processed on the unhealthy node versus zero on the freshly-started healthy node — confirming sustained traffic disruption.
A comparison table titled "Summary of Key Differences" between the unhealthy and healthy nodes. Five differences are listed: a blackhole route for 10.96.0.0/12 present only on the unhealthy node, kubelet API server timeout errors present only on the unhealthy node, conntrack entries at 1,962 versus 169, IPAMD reconcile errors at 5 versus 1, and iptables FORWARD counters at 2.4 billion packets versus 0 on the fresh healthy node. DNS configuration is identical on both nodes.

Figure 6: Healthy node comparison confirming the diagnosis. The agent compares diagnostics across both nodes and identifies five key differences — the blackhole route, elevated conntrack entries, and high FORWARD chain packet counts exist only on the affected node.
The agent synthesizes the findings into a definitive root cause determination. It identifies a fault-injection namespace on the EKS cluster that is running chaos experiments, introducing three specific network-disrupting modifications on the target node: (1) a FAULT-INJECT-DROP-POD-TO-POD iptables rule in the FORWARD chain that drops inter-pod traffic, (2) a FAULT-INJECT-DROP-SERVICE-CIDR rule that drops forwarded traffic to the Kubernetes service CIDR, and (3) a blackhole route for 10.96.0.0/12 that does not exist on healthy nodes. Together, these three modifications create a multi-vector network disruption — pods appear Running but cannot communicate with each other or reach Kubernetes services, including kube-dns.
The Root causes panel identifies one root cause: "Fault-injection workloads on node i-09ffc4a0ea5da9cb7 causing multi-vector network disruption." The explanation states that a fault-injection namespace is running chaos experiments that introduced two iptables FORWARD chain DROP rules (FAULT-INJECT-DROP-POD-TO-POD and FAULT-INJECT-DROP-SERVICE-CIDR) and a blackhole route for 10.96.0.0/12 that does not exist on healthy nodes.

Figure 7: Root cause determination. The agent traces the multi-vector network disruption to three fault-injection modifications — two iptables DROP rules and a blackhole route — deployed by a chaos experiment namespace on the target node.

Cleaning up the fault

To restore the node after the demo, connect via SSM Session Manager and run:

sudo iptables -D FORWARD -d 10.100.0.10/32 -p udp --dport 53 -j DROP
sudo iptables -D FORWARD -d 10.100.0.10/32 -p tcp --dport 53 -j DROP

Extending this pattern to other data sources

The EKS node diagnostics use case demonstrates the pattern, but the architecture generalizes to systems where the SSM Agent is running and you can define an SSM Automation runbook to collect the data you need.

For example, an EC2 instance with SSM Agent can use this same approach — collect OS-level logs, network configuration, package state, or application diagnostics through a custom or pre-built SSM Automation runbook, upload results to S3, and expose them through MCP tools. The same applies to ECS container instances (Docker daemon logs, ECS agent state, iptables), on-premises servers registered via SSM Hybrid Activations, or managed nodes in your fleet.

The pattern also extends beyond SSM-managed hosts. Network devices can be reached through API calls to their management planes, databases through read-only diagnostic queries, and third-party APM tools through vendor API integrations. In each case, the same three-step approach holds: identify the unreachable data, build an MCP server that wraps safe access to it, and connect it to AWS DevOps Agent.

When to use this approach
This pattern works well for incident response where diagnostic data lives outside AWS DevOps Agent’s native reach, fleet-wide triage where manual access to individual systems is impractical, and cross-source correlation where evidence spans multiple log sources.

It is not a replacement for continuous monitoring (use CloudWatch Container Insights or Prometheus for real-time alerting), log shipping (if you have compliance requirements for continuous retention), or native integrations where the agent already has access to the data source.

The reference implementation requires SSM Agent running on the nodes with appropriate IAM permissions. It is a proof of concept — validate it in non-production environments before using it with production workloads.

Clean up

Cost considerations: This solution uses AWS Lambda, Amazon S3, AWS KMS, Amazon Cognito, and Amazon Bedrock AgentCore Gateway. Costs vary based on usage. Lambda charges apply per invocation and duration. S3 charges apply for log storage. KMS charges a per-key monthly fee plus per-request charges. Cognito charges per monthly active user. AgentCore Gateway pricing is based on API calls. For current pricing details, see the AWS Pricing page for each service. To minimize costs during evaluation, delete the stack when not in use.

Remove the deployed resources by running cdk destroy from the repository root. The S3 log bucket uses a RETAIN removal policy — delete it manually after stack destruction if needed.

Conclusion

MCP provides a standardized extensibility mechanism that lets you bridge visibility gaps in AWS DevOps Agent without modifying the agent itself. The pattern is straightforward: identify the unreachable data source, build an MCP server that wraps safe and structured access to it, and connect it to AWS DevOps Agent through Amazon Bedrock AgentCore Gateway. The agent handles the reasoning. The MCP server handles the data access.

To get started:

  • Deploy the reference implementation (sample-eks-node-diagnostics-mcp repository) in a non-production environment.
  • Review the MCP specification (MCP specification).
  • Explore the Amazon EKS troubleshooting documentation (Amazon EKS troubleshooting documentation).
  • Connect custom MCP servers to AWS DevOps Agent — see the Connecting MCP Servers guide in the AWS DevOps Agent documentation.
  • Set up AgentCore Gateway — see the Amazon Bedrock AgentCore Gateway quick start guide.

About the author

Shyam Kulkarni

Shyam Kulkarni

Shyam Kulkarni is a Sr. Technical Account Manager at AWS, where he helps enterprise customers design and implement cloud-native architectures with a focus on container orchestration, platform engineering, and observability at scale. He advises organizations on strategic modernization initiatives and is passionate about architecting AI-native systems, including agentic AI platforms and scalable AI infrastructure. Outside of work, Shyam is an avid travel and landscape photographer who enjoys exploring new destinations and capturing dramatic natural scenery. He’s also an enthusiastic home cook and baker who loves experimenting with new recipes, flavors, and techniques in the kitchen. When not behind a camera or in the kitchen, you’ll find him hiking remote trails.