Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=jwLDx60Ffvs
Hanna Rosin With Tom Nichols Live on Radio Atlantic | The Atlantic Festival 2024
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=kEf518GJglc
The State of Justice Reform with CNN’s Jake Tapper, C.J. Rice, and more | The Atlantic Festival 2024
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=N_P4B7dnDys
Helping Children Overcome the Mental-Health Crisis | The Atlantic Festival 2024
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=OKO3JoL4iAI
Security updates for Monday
Post Syndicated from jake original https://lwn.net/Articles/991377/
Security updates have been issued by AlmaLinux (expat, fence-agents, firefox, libnbd, openssl, pcp, ruby:3.3, and thunderbird), Debian (ruby-saml), Fedora (aardvark-dns, chromium, expat, jupyterlab, less, openssl, python-jupyterlab-server, python-notebook, python3-docs, and python3.12), Gentoo (calibre, curl, Emacs, org-mode, Exo, file, GPL Ghostscript, gst-plugins-good, liblouis, Mbed TLS, OpenVPN, Oracle VirtualBox, PJSIP, Portage, PostgreSQL, pypy, pypy3, Rust, Slurm, stb, VLC, and Xen), SUSE (container-suseconnect, ffmpeg-4, kernel, libpcap, python3, python310, python36, and wpa_supplicant), and Ubuntu (firefox, linux, linux-aws, linux-aws-hwe, linux-azure, linux-azure-4.15, linux-gcp, linux-gcp-4.15, linux-hwe, linux-kvm, linux-oracle, linux-azure, and linux-ibm-5.15, linux-oracle-5.15).
Start auditing and controlling the AI models accessing your content
Post Syndicated from Sam Rhea original https://blog.cloudflare.com/cloudflare-ai-audit-control-ai-content-crawlers
Site owners have lacked the ability to determine how AI services use their content for training or other purposes. Today, Cloudflare is releasing a set of tools to make it easy for site owners, creators, and publishers to take back control over how their content is made available to AI-related bots and crawlers. All Cloudflare customers can now audit and control how AI models access the content on their site.
This launch starts with a detailed analytics view of the AI services that crawl your site and the specific content they access. Customers can review activity by AI provider, by type of bot, and which sections of their site are most popular. This data is available to every site on Cloudflare and does not require any configuration.
We expect that this new level of visibility will prompt teams to make a decision about their exposure to AI crawlers. To help give them time to make that decision, Cloudflare now provides a one-click option in our dashboard to immediately block any AI crawlers from accessing any site. Teams can then use this “pause” to decide if they want to allow specific AI providers or types of bots to proceed. Once that decision is made, those administrators can use new filters in the Cloudflare dashboard to enforce those policies in just a couple of clicks.
Some customers have already made decisions to negotiate deals directly with AI companies. Many of those contracts include terms about the frequency of scanning and the type of content that can be accessed. We want those publishers to have the tools to measure the implementation of these deals. As part of today’s announcement, Cloudflare customers can now generate a report with a single click that can be used to audit the activity allowed in these arrangements.
We also think that sites of any size should be able to determine how they want to be compensated for the usage of their content by AI models. Today’s announcement previews a new Cloudflare monetization feature which will give site owners the tools to set prices, control access, and capture value for the scanning of their content.
What is the problem?
Until recently, bots and scrapers on the Internet mostly fell into two clean categories: good and bad. Good bots, like search engine crawlers, helped audiences discover your site and drove traffic to you. Bad bots tried to take down your site, jump the queue ahead of your customers, or scrape competitive data. We built the Cloudflare Bot Management platform to give you the ability to distinguish between those two broad categories and to allow or block them.
The rise of AI Large Language Models (LLMs) and other generative tools created a murkier third category. Unlike malicious bots, the crawlers associated with these platforms are not actively trying to knock your site offline or to get in the way of your customers. They are not trying to steal sensitive data; they just want to scan what is already public on your site.
However, unlike helpful bots, these AI-related crawlers do not necessarily drive traffic to your site. AI Data Scraper bots scan the content on your site to train new LLMs. Your material is then put into a kind of blender, mixed up with other content, and used to answer questions from users without attribution or the need for users to visit your site. Another type of crawler, AI Search Crawler bots, scan your content and attempt to cite it when responding to a user’s search. The downside is that those users might just stay inside of that interface, rather than visit your site, because an answer is assembled on the page in front of them.
This murkiness leaves site owners with a hard decision to make. The value exchange is unclear. And site owners are at a disadvantage while they play catch up. Many sites allowed these AI crawlers to scan their content because these crawlers, for the most part, looked like “good” bots — only for the result to mean less traffic to their site as their content is repackaged in AI-written answers.
We believe this poses a risk to an open Internet. Without the ability to control scanning and realize value, site owners will be discouraged to launch or maintain Internet properties. Creators will stash more of their content behind paywalls and the largest publishers will strike direct deals. AI model providers will in turn struggle to find and access the long tail of high-quality content on smaller sites.
Both sides lack the tools to create a healthy, transparent exchange of permissions and value. Starting today, Cloudflare equips site owners with the services they need to begin fixing this. We have broken out a series of steps we recommend all of our customers follow to get started.
Step 1: Understand how AI models use your site
Every site on Cloudflare now has access to a new analytics view that summarizes the crawling behavior of popular and known AI services. You can begin reviewing this information to understand the AI scanning of your content by selecting a site in your dashboard and navigating to the AI Audit tab in the left-side navigation bar.
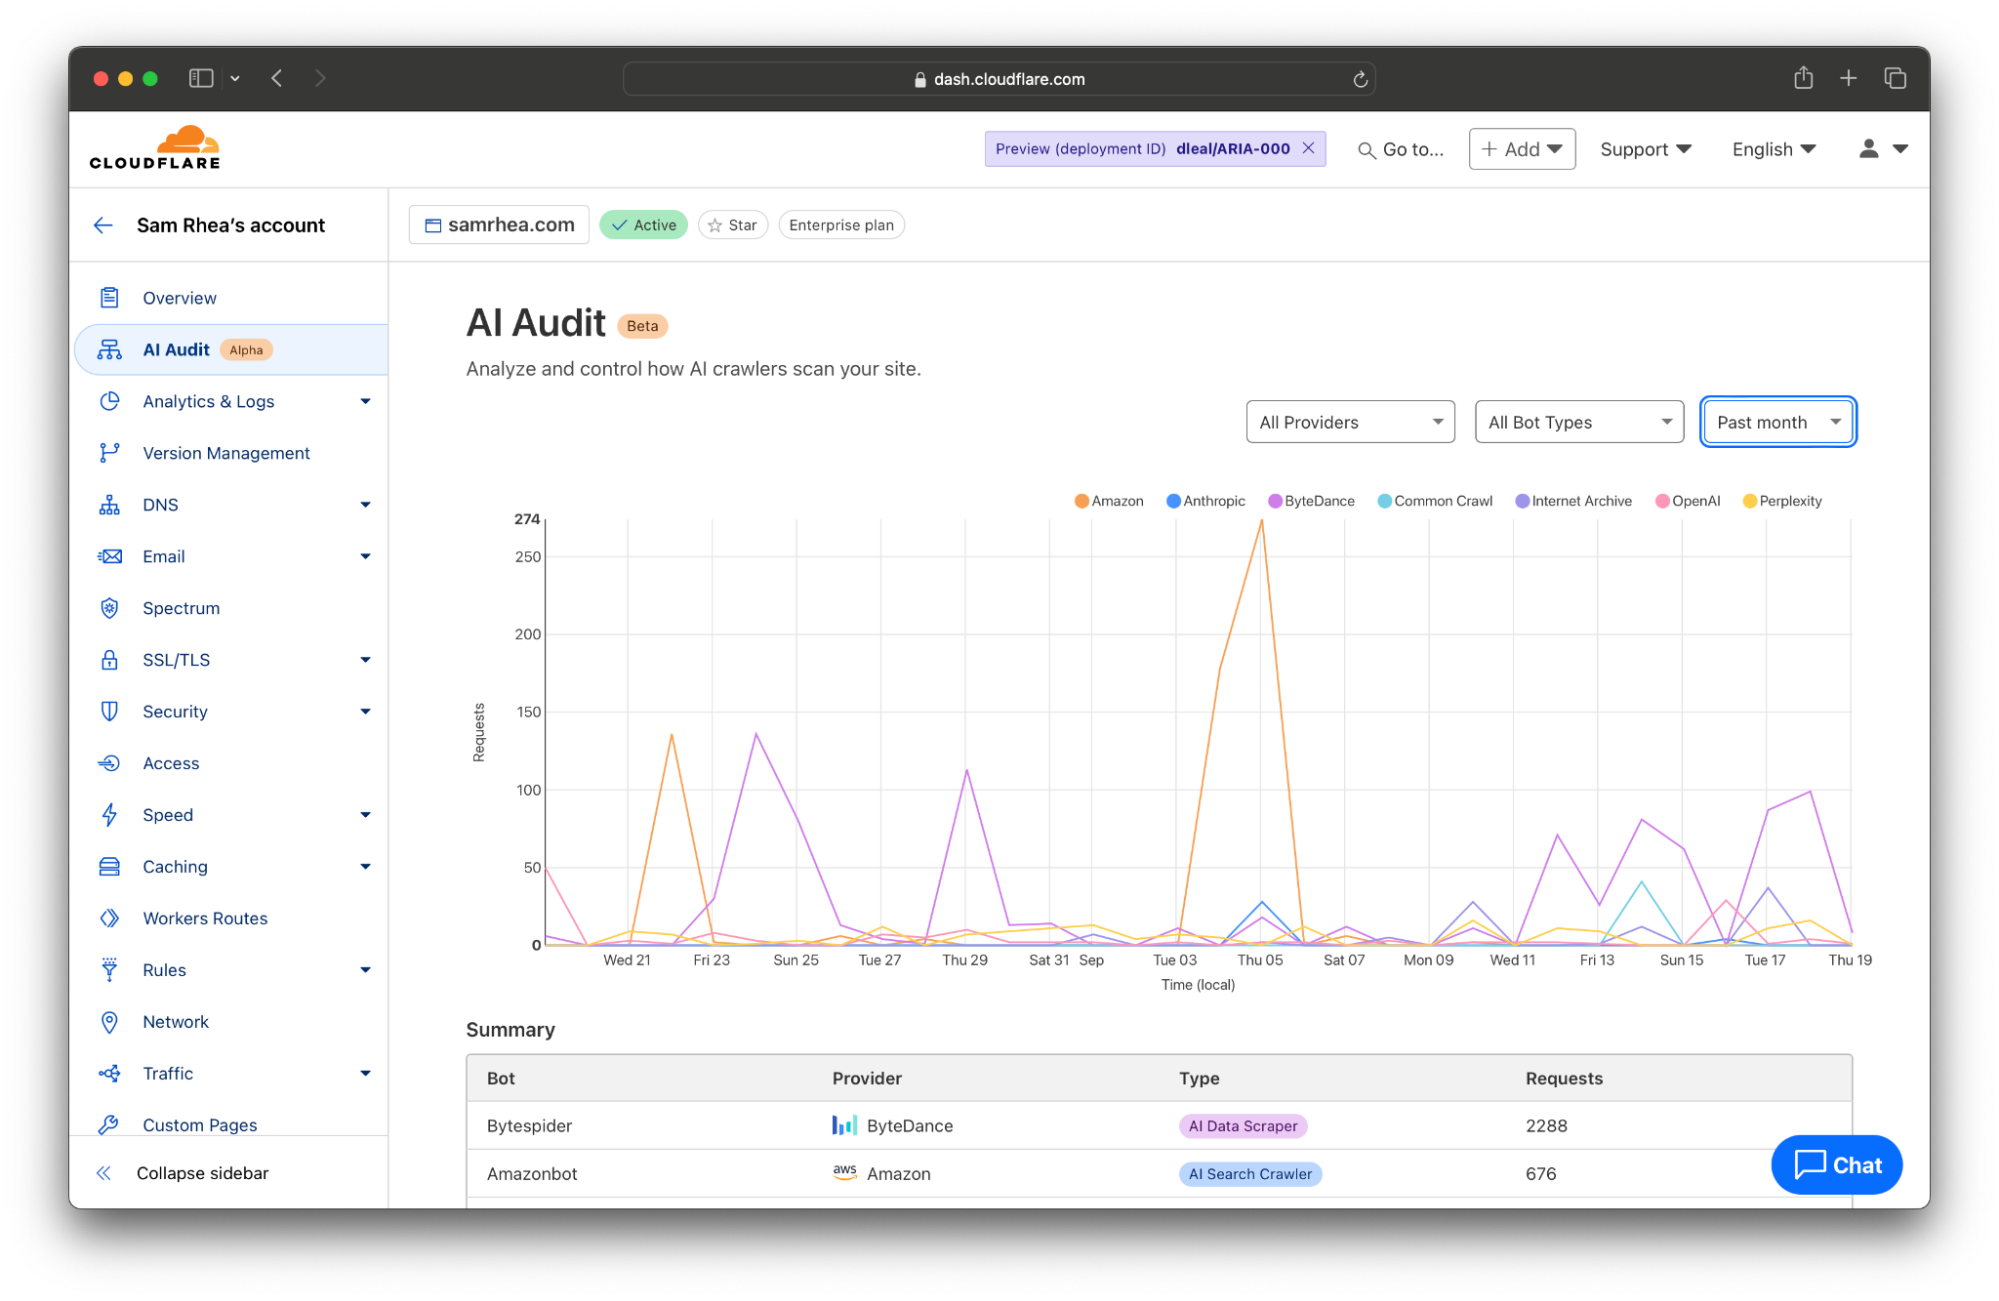
When AI model providers access content on your site, they rely on automated tools called “bots” or “crawlers” to scan pages. The bot will request the content of your page, capture the response, and store it as part of a future data training set or remember it for AI search engine results in the future.
These bots often identify themselves to your site (and Cloudflare’s network) by including an HTTP header in their request called a User Agent. Although, in some cases, a bot from one of these AI services might not send the header and Cloudflare instead relies on other heuristics like IP address or behavior to identify them.
When the bot does identify itself, the header will contain a string of text with the bot name. For example, Anthropic sometimes crawls sites on the Internet with a bot called ClaudeBot. When that service requests the content of a page from your site on Cloudflare, Cloudflare logs the User Agent as ClaudeBot.
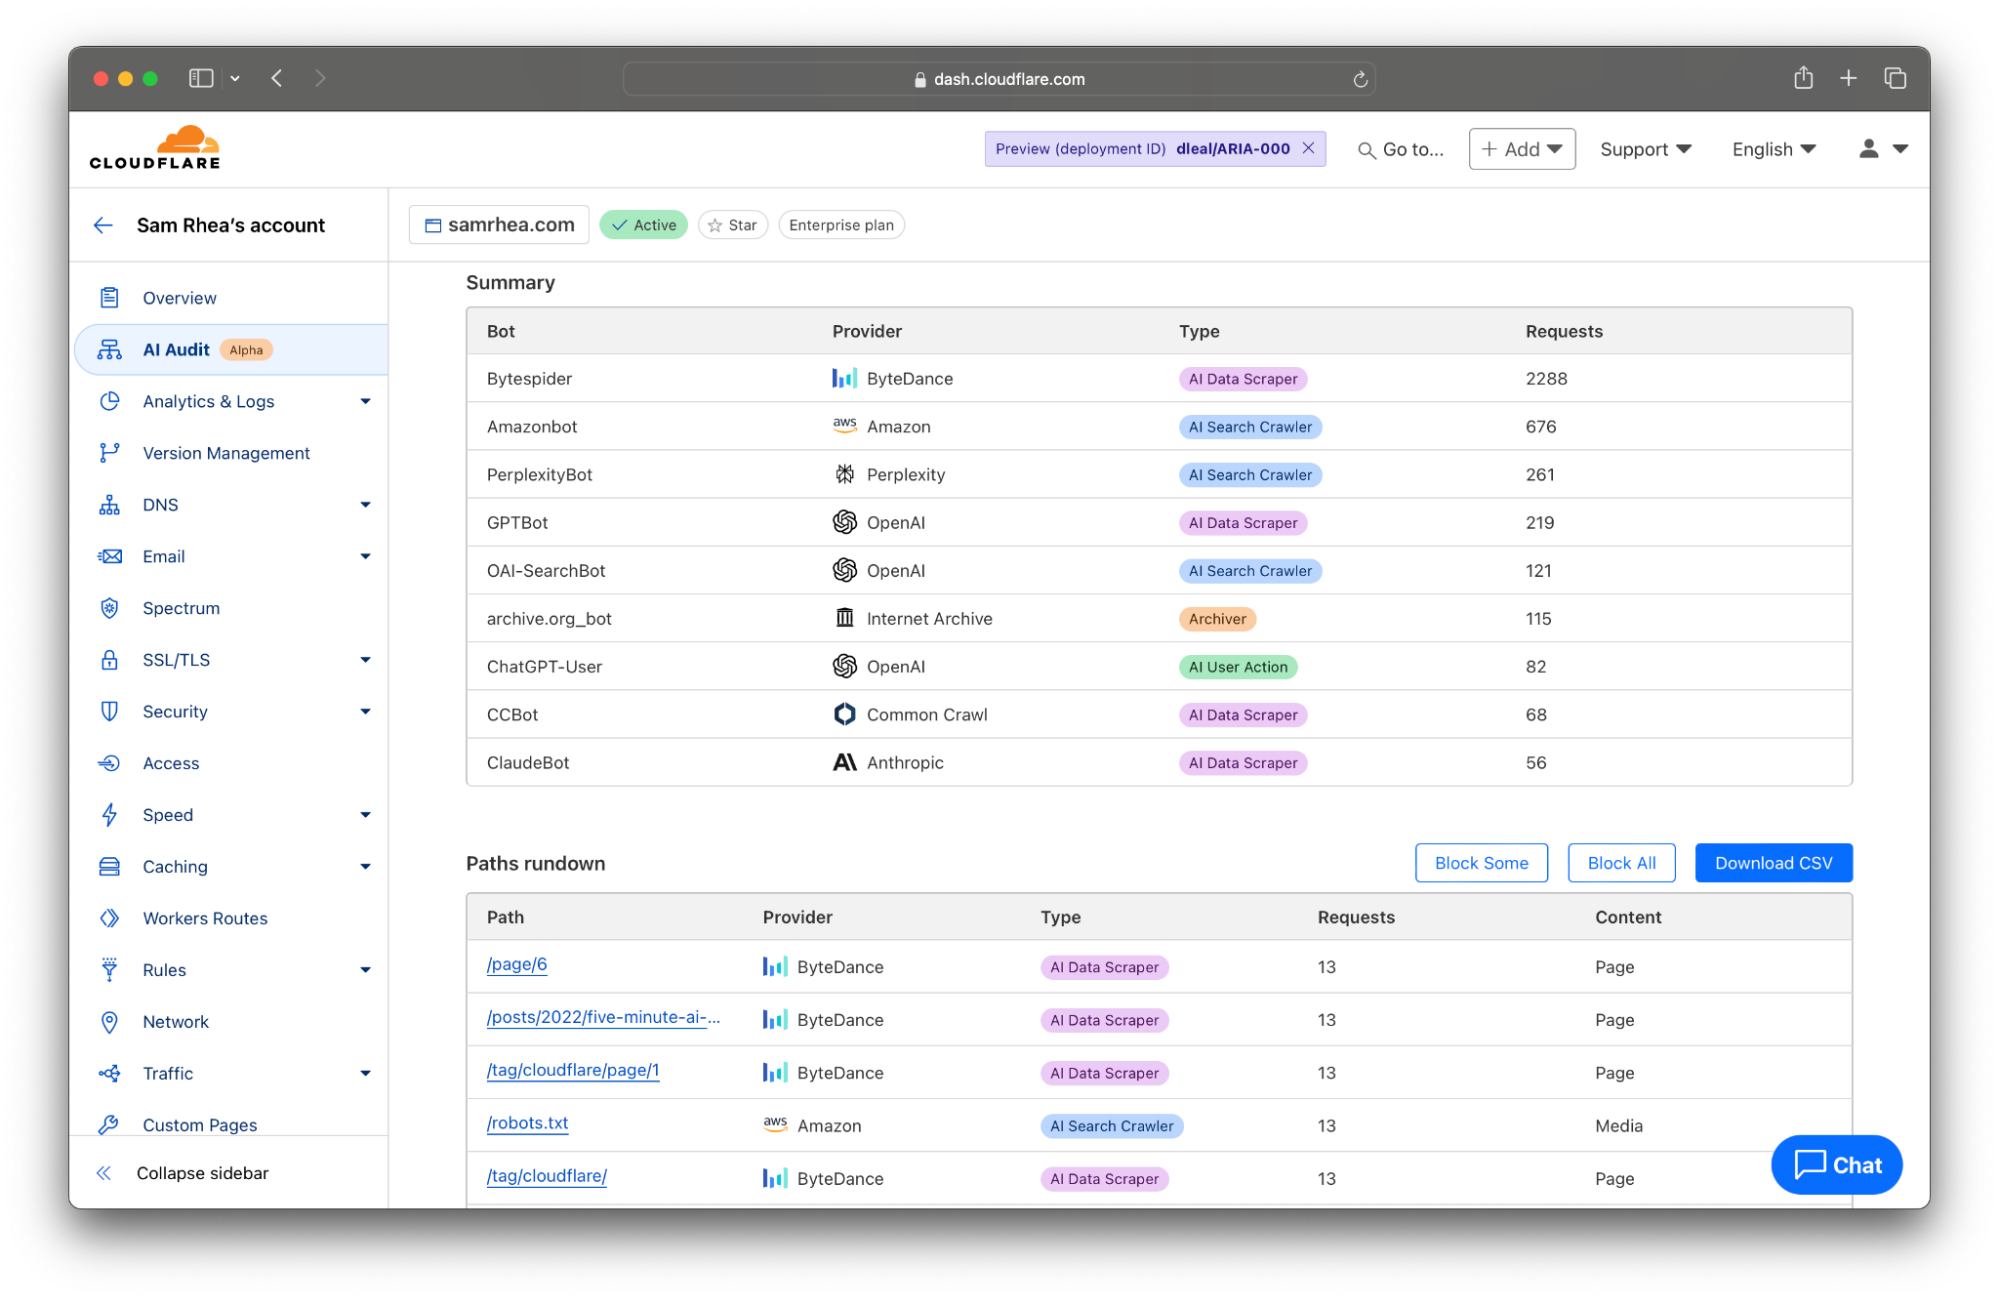
Cloudflare takes the logs gathered from visits to your site and looks for user agents that match known AI bots and crawlers. We summarize the activity of individual crawlers and also provide you with filters to review just the activities of specific AI platforms. Many AI firms rely on multiple crawlers that serve distinct purposes. When OpenAI scans sites for data scraping, they rely on GPTBot, but when they crawl sites for their new AI search engine, they use OAI-SearchBot.
And those differences matter. Scanning from different bot types can impact traffic to your site or the attribution of your content. AI search engines will often link to sites as part of their response, potentially sending visitors to your destination. In that case, you might be open to those types of bots crawling your Internet property. AI Data Scrapers, on the other hand, just exist to read as much of the Internet as possible to train future models or improve existing ones.
We think that you deserve to know why a bot is crawling your site in addition to when and how often. Today’s release gives you a filter to review bot activity by categories like AI Data Scraper, AI Search Crawler, and Archiver.
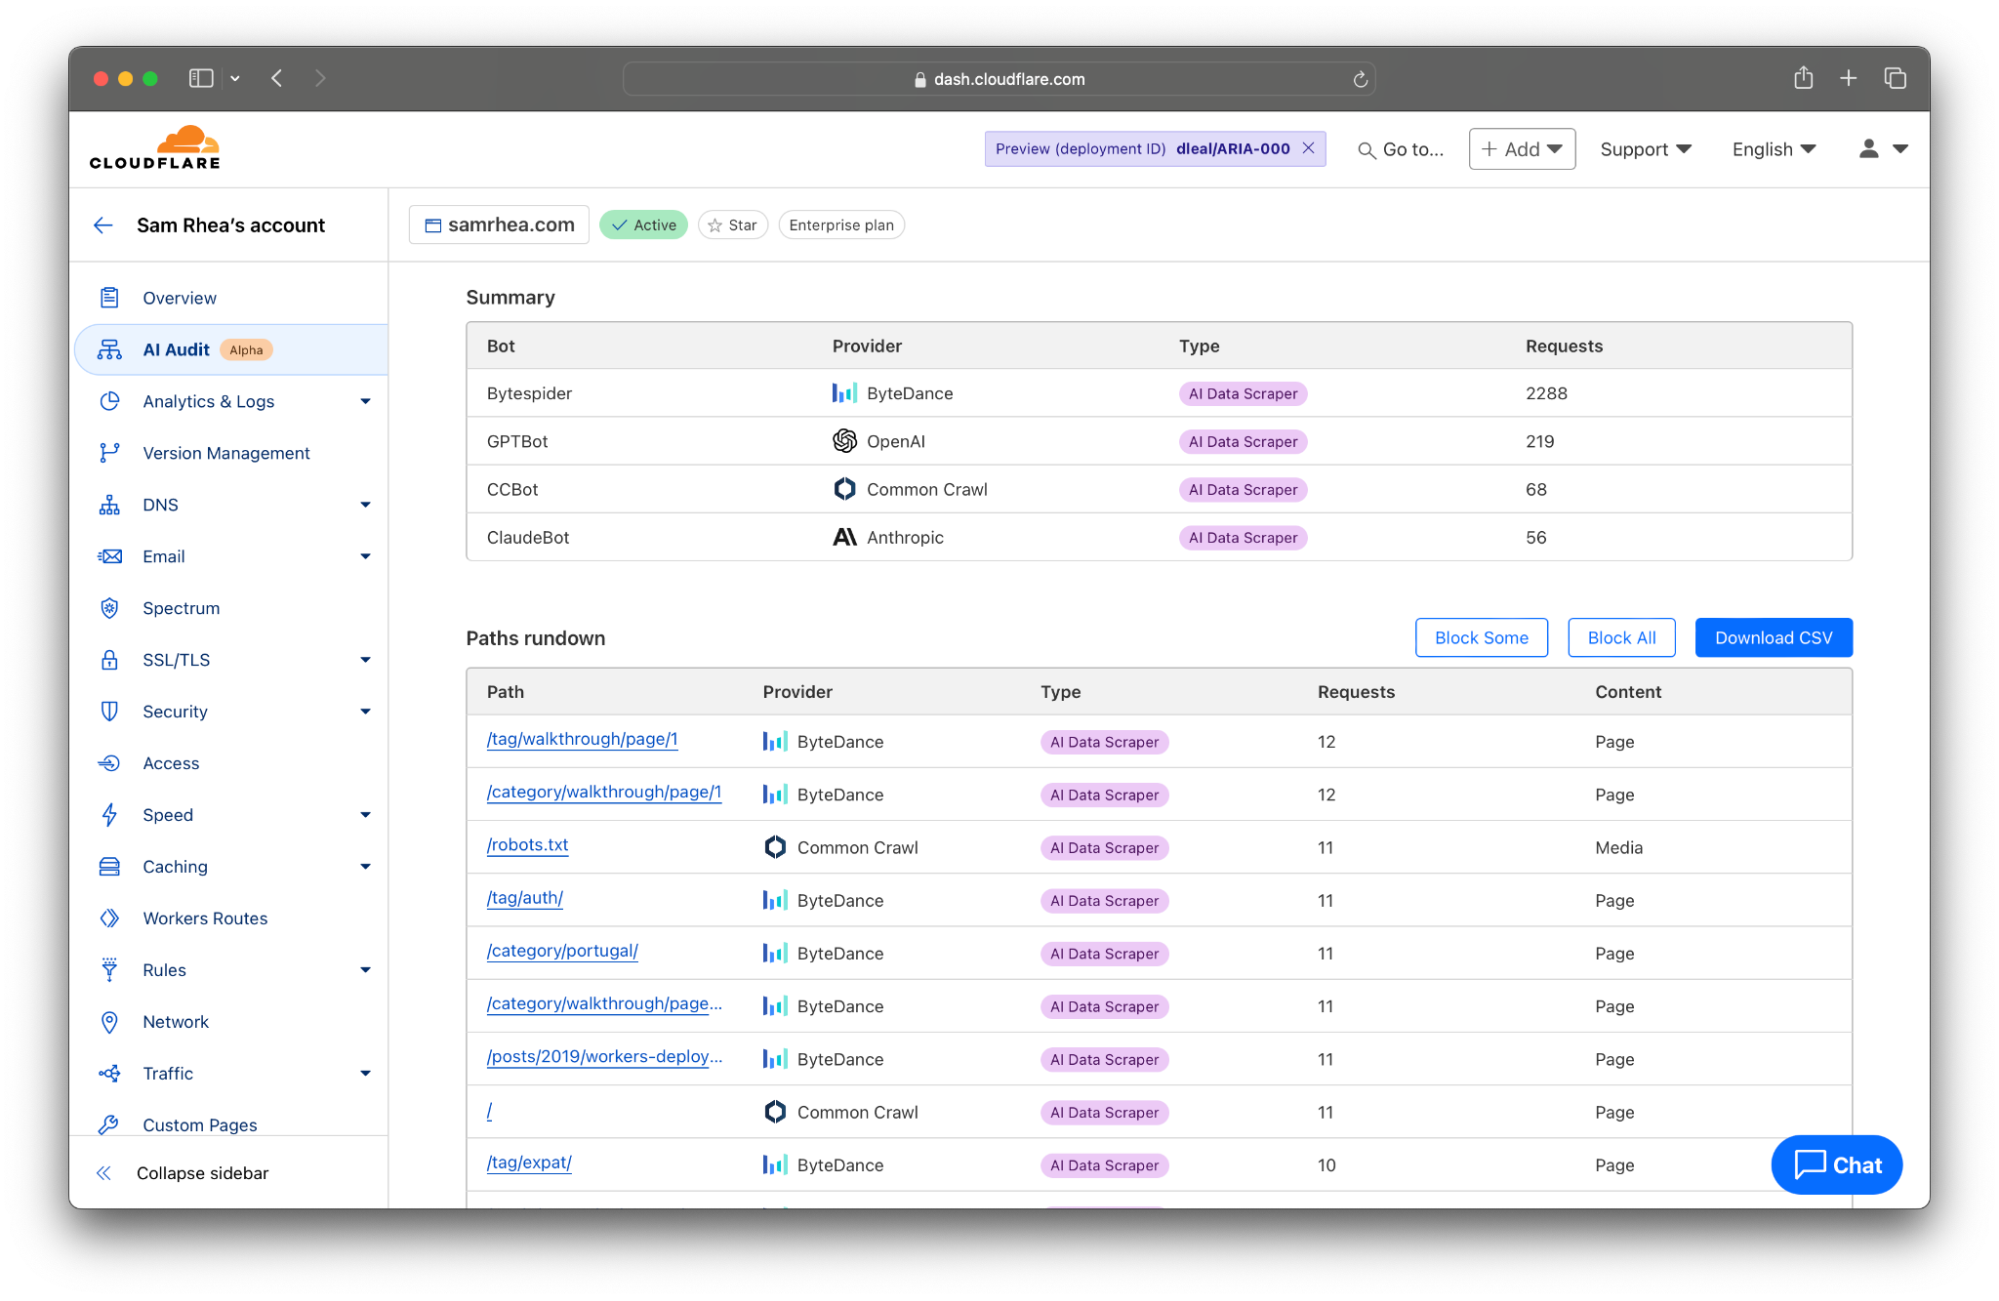
With this data, you can begin analyzing how AI models access your site. That information might be overwhelming, especially if your team has not had time yet to decide how you want to handle AI scanning of your content. If you find yourself unsure on how to respond, proceed to Step 2.
Step 2: Give yourself a pause to decide what to do next
We talked to several organizations who know their sites are valuable destinations for AI crawlers, but they do not yet know what to do about it. These teams need a “time out” so they can make an informed decision about how they make their data available to these services.
Cloudflare gives you that easy button right now. Any customer on any plan can choose to block all AI bots and crawlers to give yourself a pause while you decide what you do want to allow.
To implement that option, navigate to the Bots section under the Security tab of the Cloudflare Dashboard. Follow the blue link in the top right corner to configure how Cloudflare’s proxy handles bot traffic. Next, toggle the button in the “Block AI Scrapers and Crawlers” card to the “On” position.
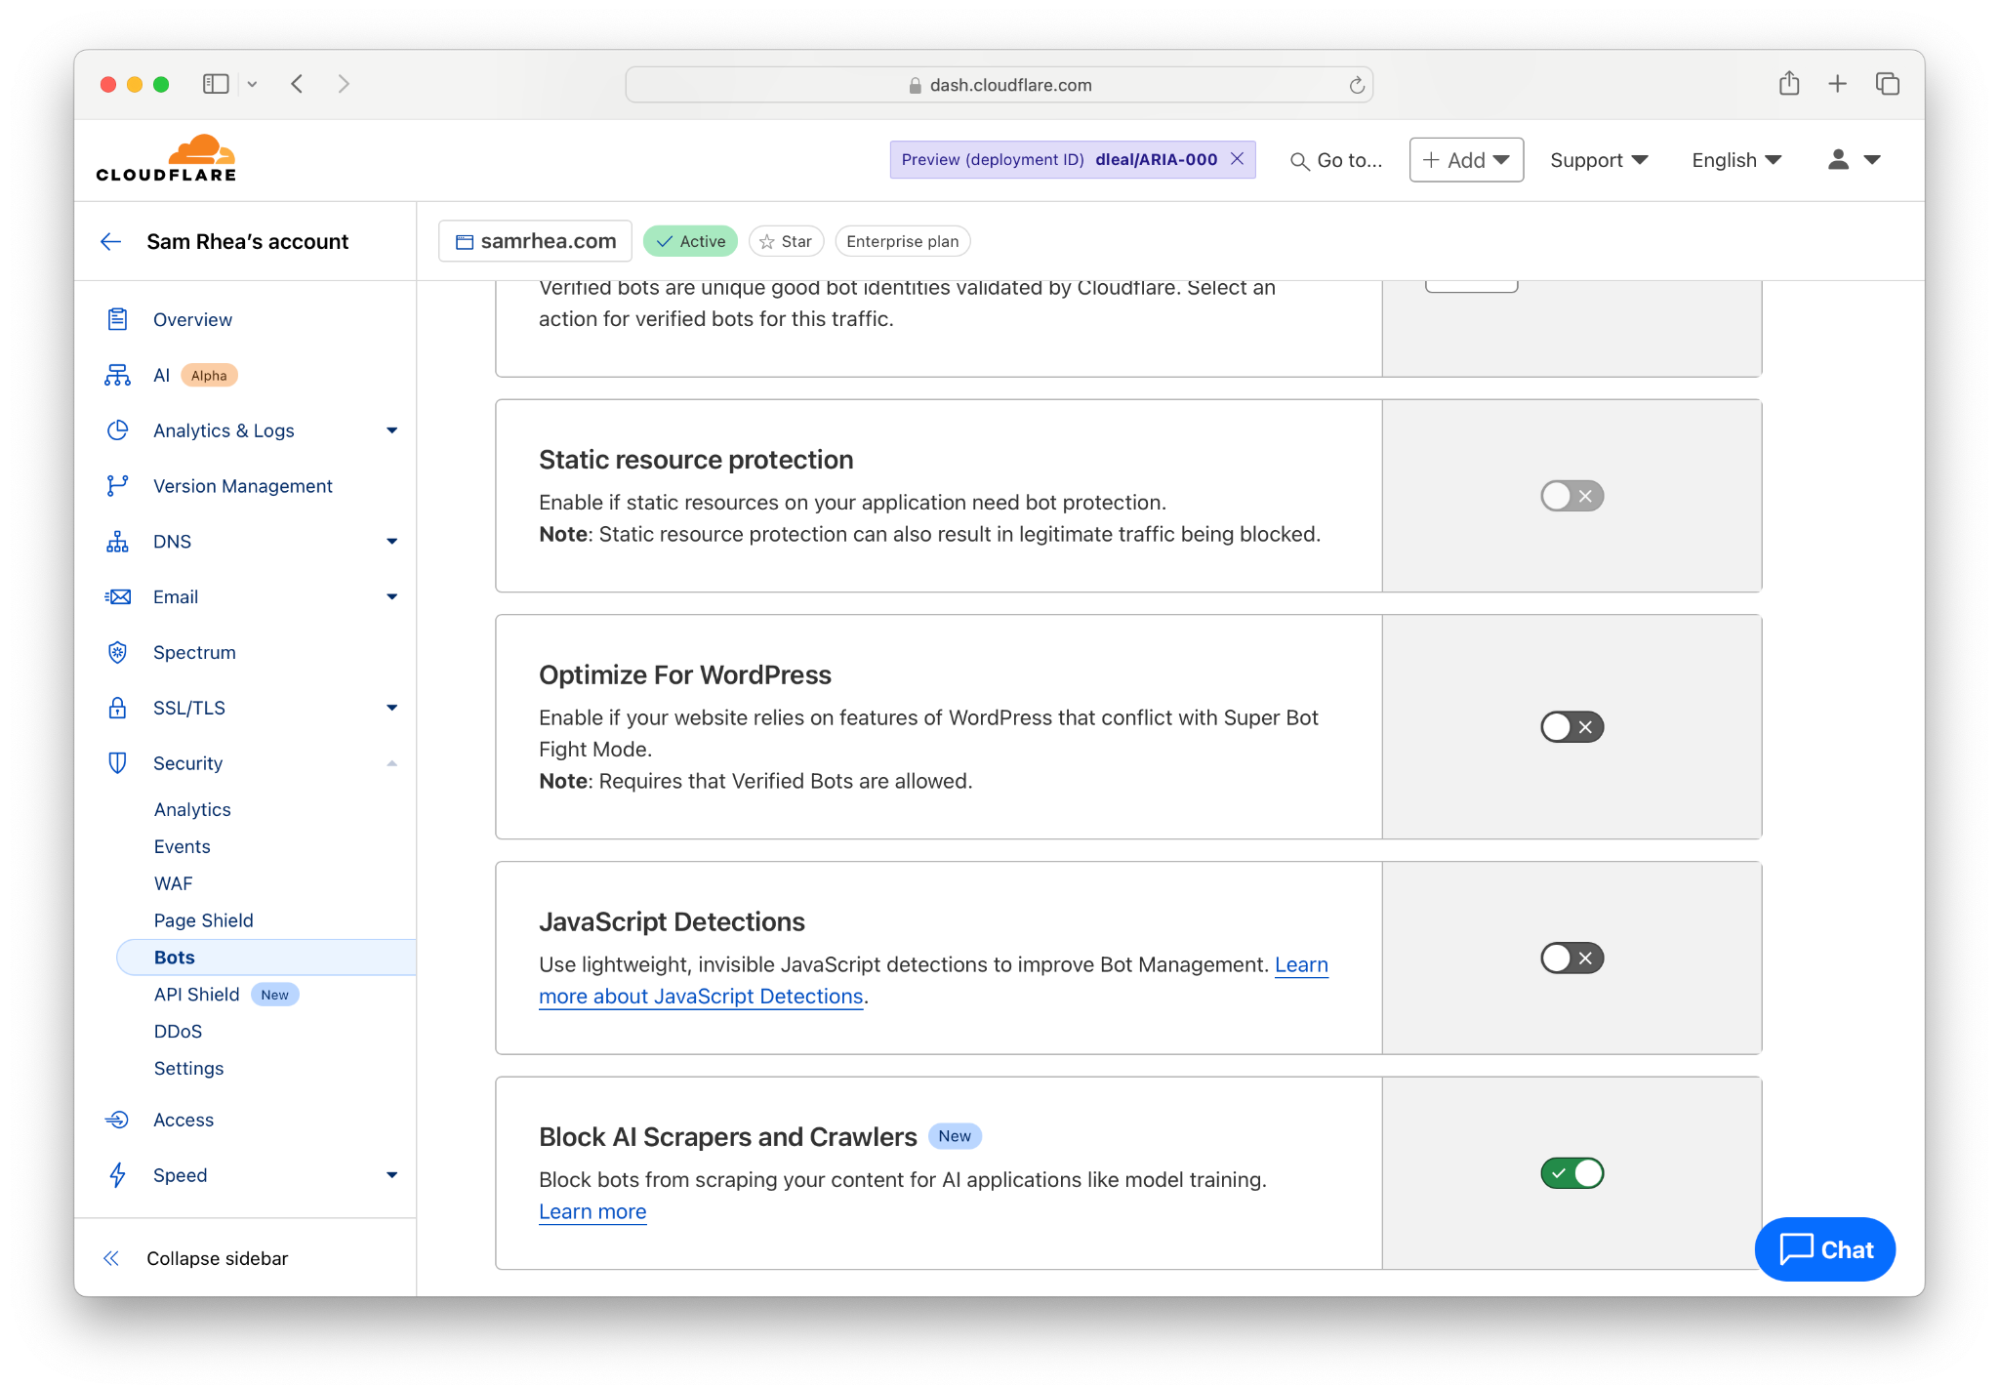
The one-click option blocks known AI-related bots and crawlers from accessing your site based on a list that Cloudflare maintains. With a block in place, you and your team can make a less rushed decision about what to do next with your content.
Step 3: Control the bots you do want to allow
The pause button buys time for your team to decide what you want the relationship to be between these crawlers and your content. Once your team has reached a decision, you can begin relying on Cloudflare’s network to implement that policy.
If that decision is “we are not going to allow any crawling,” then you can leave the block button discussed above toggled to “On”. If you want to allow some selective scanning, today’s release provides you with options to permit certain types of bots, or just bots from certain providers, to access your content.
For some teams, the decision will be to allow the bots associated with AI search engines to scan their Internet properties because those tools can still drive traffic to the site. Other organizations might sign deals with a specific model provider, and they want to allow any type of bot from that provider to access their content. Customers can now navigate to the WAF section of the Cloudflare dashboard to implement these types of policies.
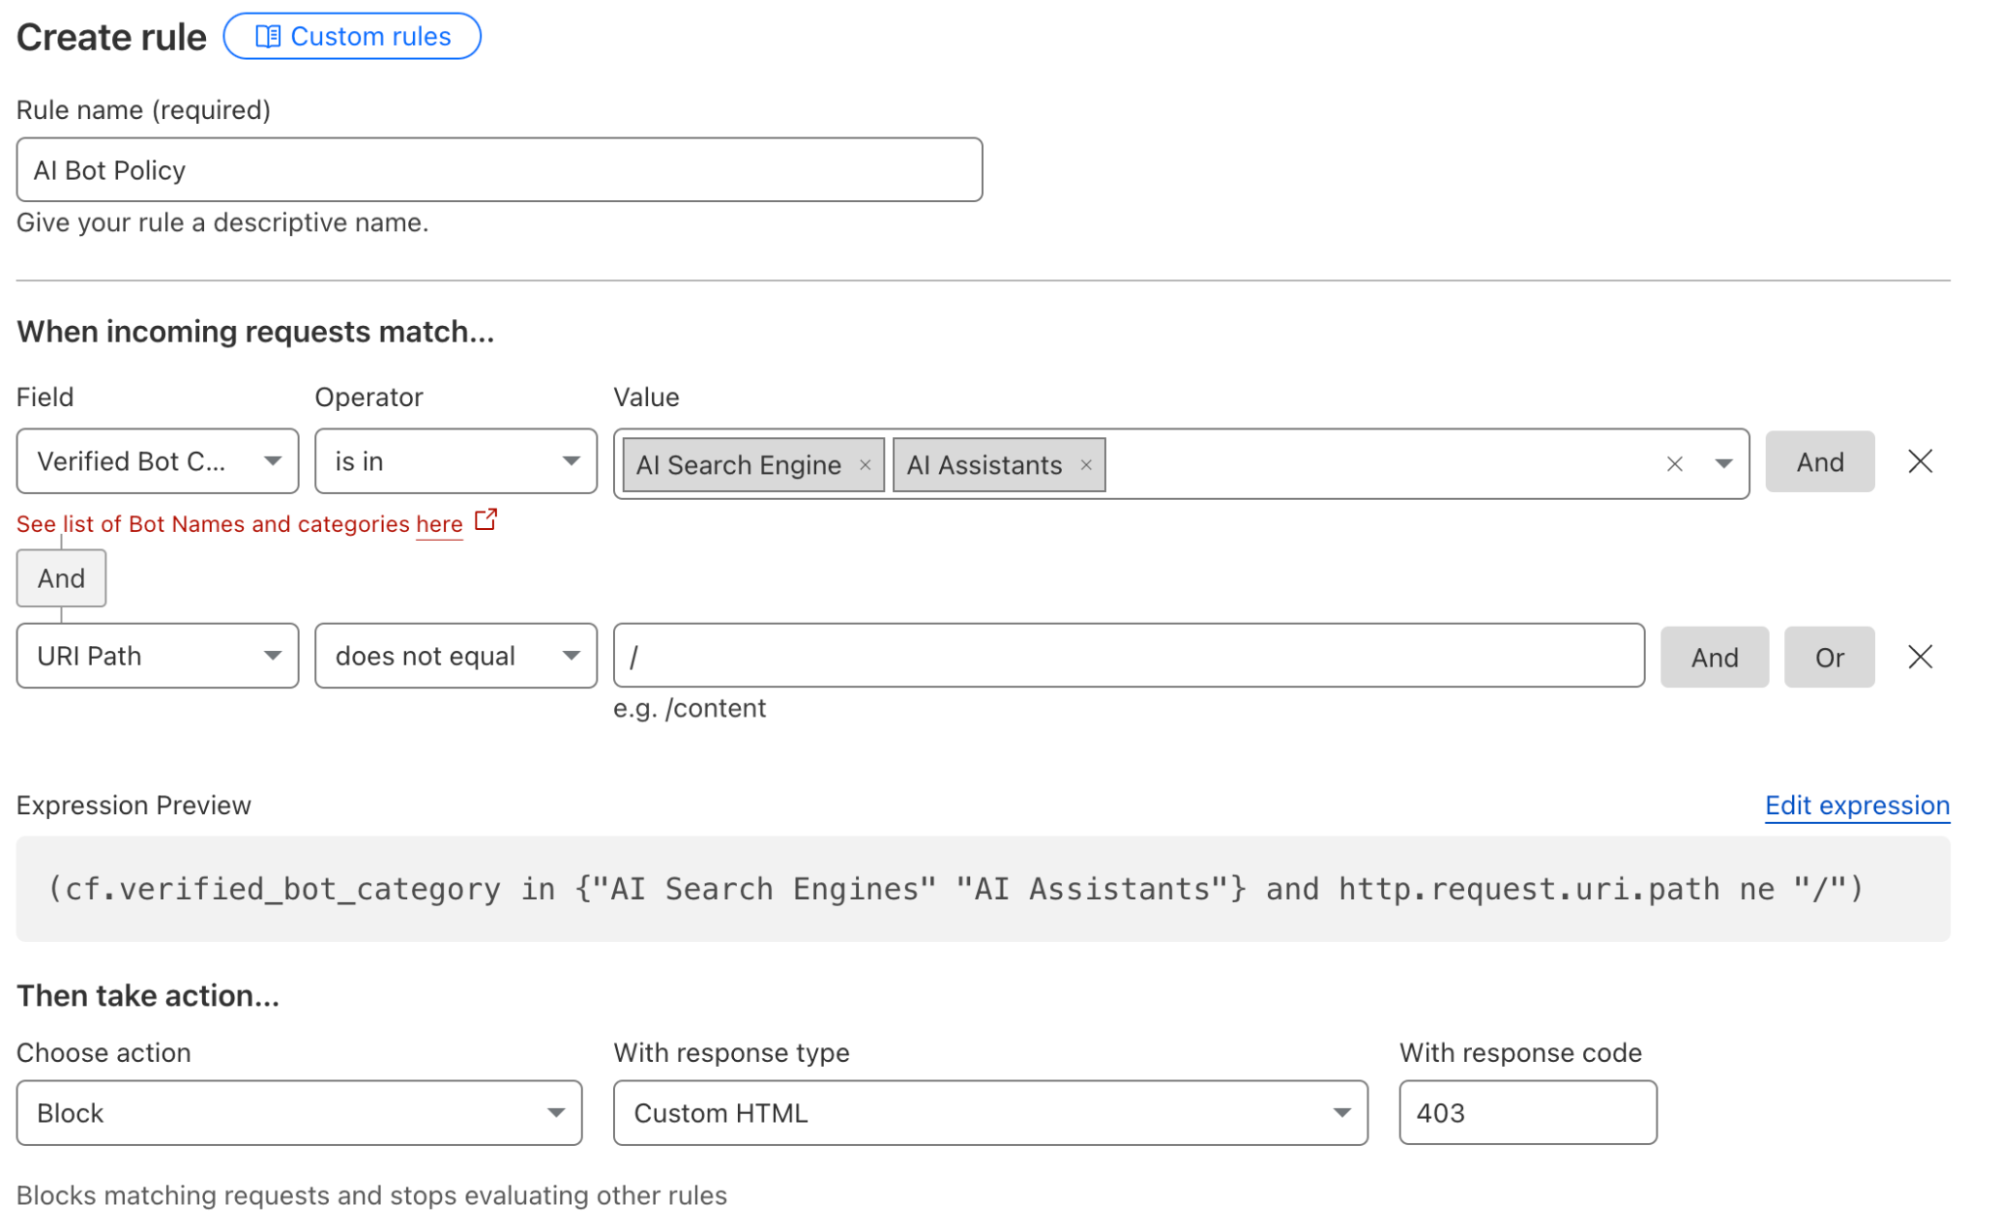
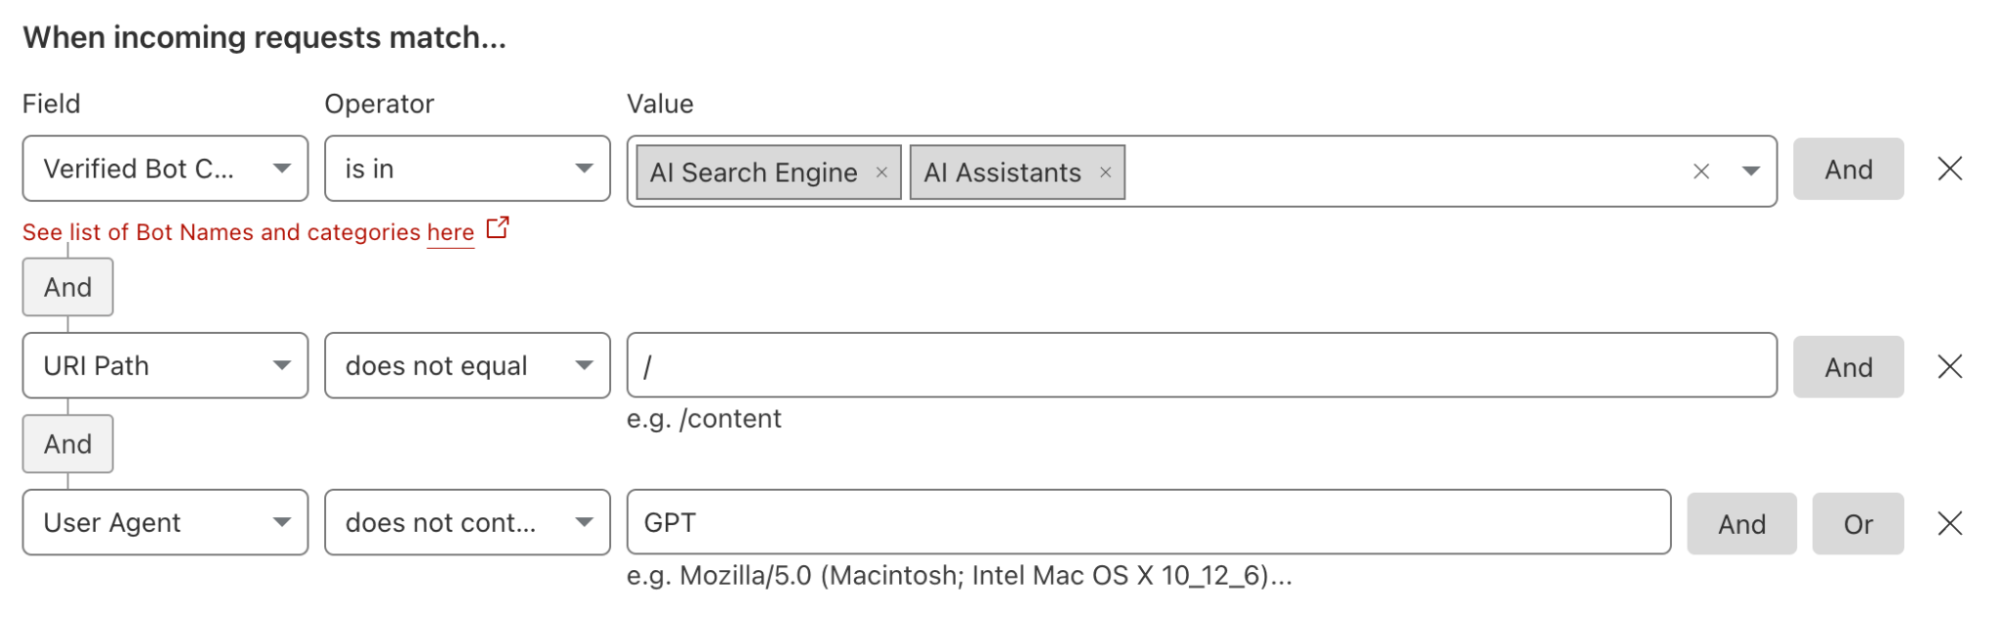
Administrators can also create rules that would, for example, block all AI bots except for those from a specific platform. Teams can deploy these types of filters if they are skeptical of most AI platforms but comfortable with one AI model provider and its policies. These types of rules can also be used to implement contracts where a site owner has negotiated to allow scanning from a single provider. The site administrator would need to create a rule to block all types of AI-related bots and then add an exception that allows the specific bot or bots from their AI partner.
We also recommend that customers consider updating their Terms of Service to cover this new use case in addition to applying these new filters. We have documented the steps we suggest that “good citizen” bots and crawlers take with respect to robots.txt files. As an extension of those best practices, we are adding a new section to that documentation where we provide a sample Terms of Service section that site owners can consider using to establish that AI scanning needs to follow the policies you have defined in your robots.txt file.
Step 4: Audit your existing scanning arrangements
An increasing number of sites are signing agreements directly with model providers to license consumption of their content in exchange for payment. Many of those deals contain provisions that determine the rate of crawling for certain sections or entire sites. Cloudflare’s AI Audit tab provides you with the tools to monitor those kinds of contracts.
The table at the bottom of the AI Audit tool now lists the most popular content on your site ranked by the count of scans in the time period from the filter set at the top of the page. You can click the Export to CSV button to quickly download a file with the details presented here that you can use to discuss any discrepancies with the AI platform that you are allowing to access your content.
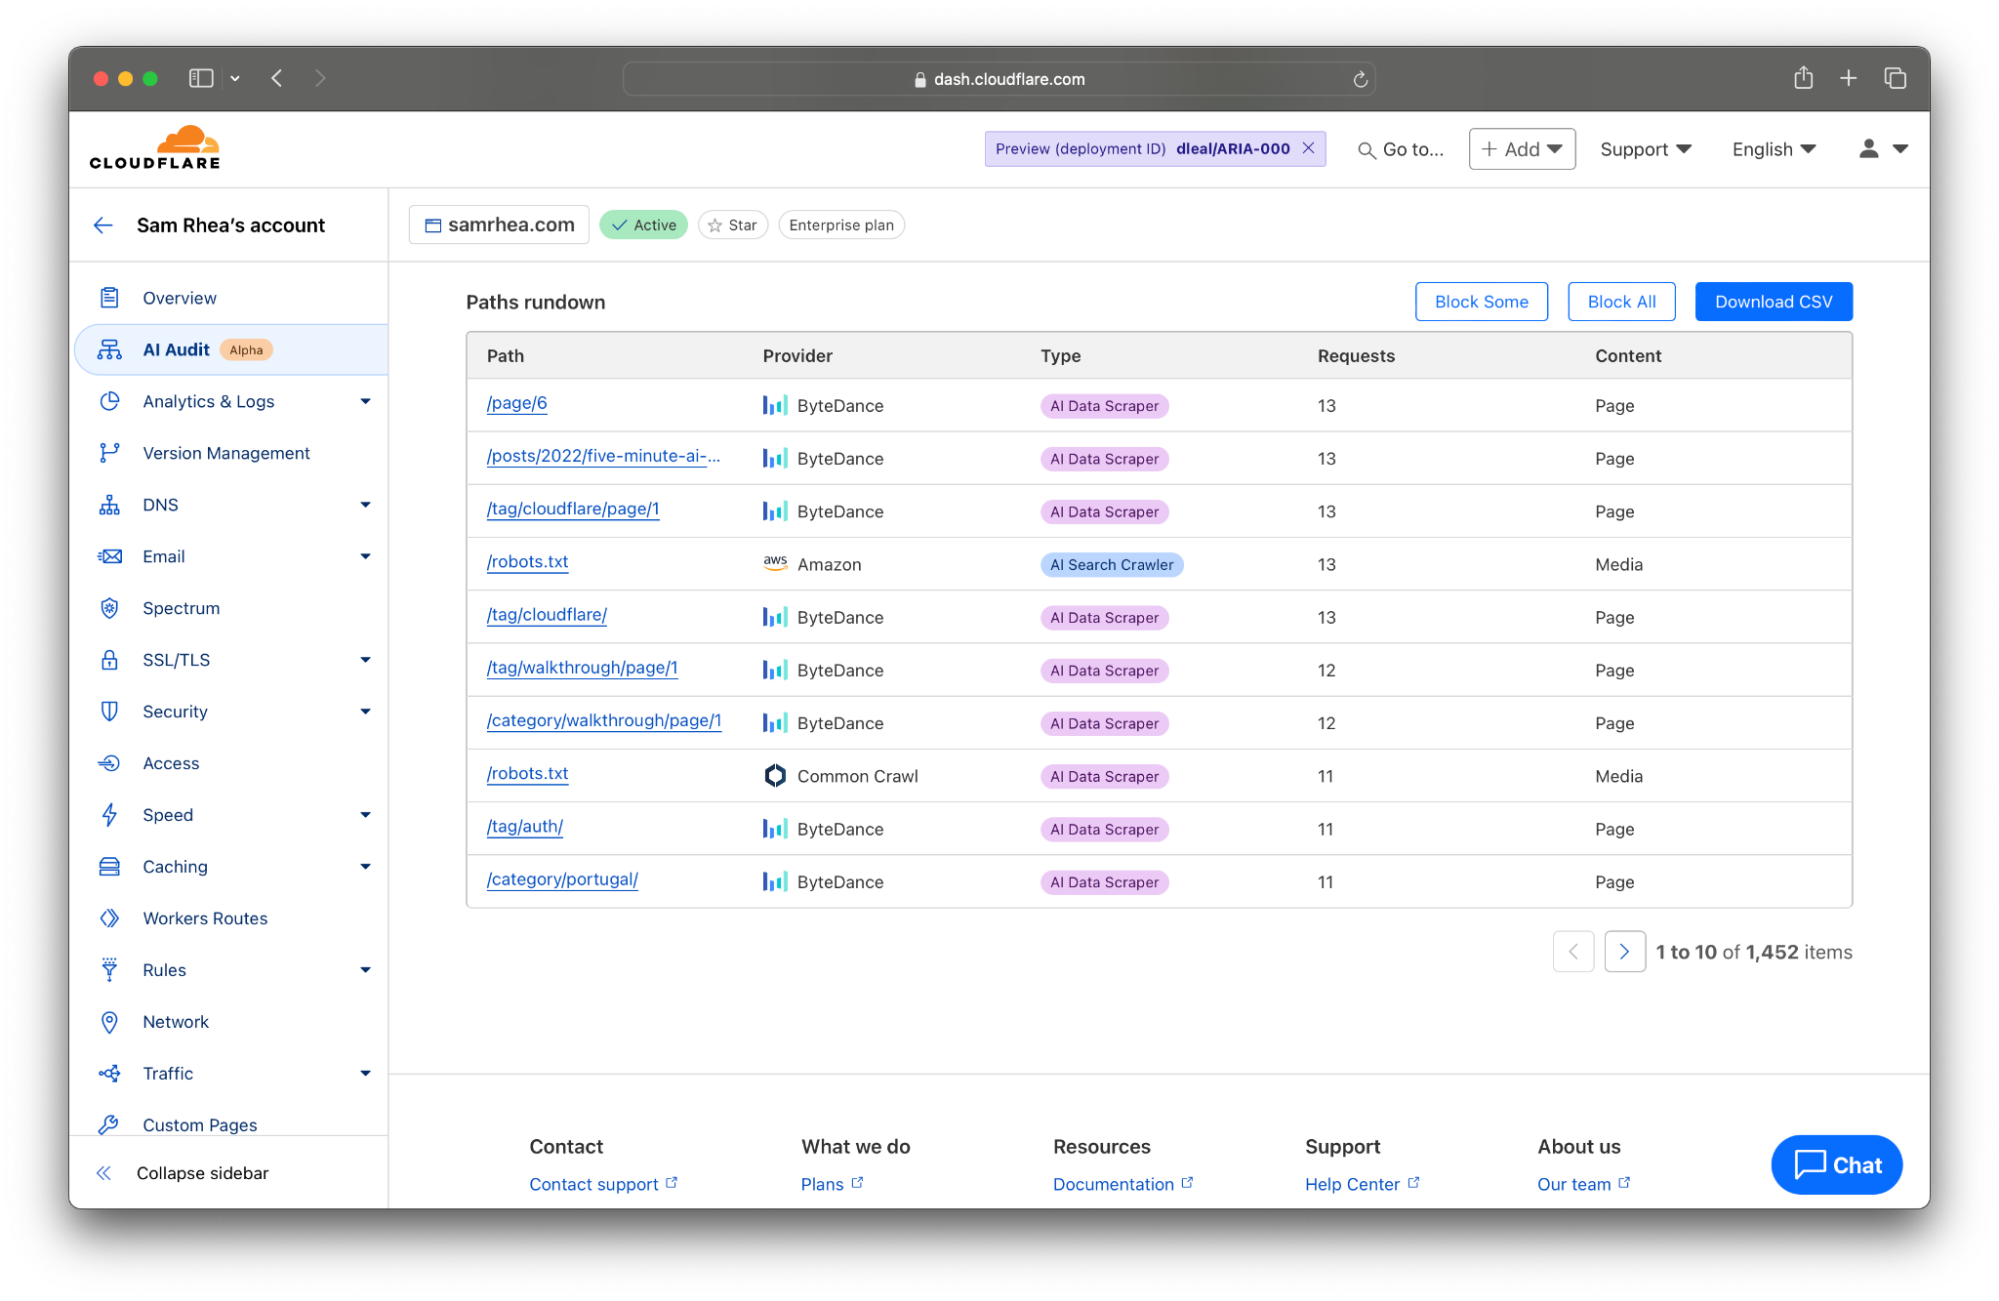
Today, the data available to you represents key metrics we have heard from customers in these kinds of arrangements: requests against certain pages and requests against the entire site.
Step 5: Prepare your site to capture value from AI scanning
Not everyone has the time or contacts to negotiate deals with AI companies. Up to this point, only the largest publishers on the Internet have the resources to set those kinds of terms and get paid for their content.
Everyone else has been left with two basic choices on how to handle their data: block all scanning or allow unrestricted access. Today’s releases give content creators more visibility and control than just those two options, but the long tail of sites on the Internet still lack a pathway to monetization.
We think that sites of any size should be fairly compensated for the use of their content. Cloudflare plans to launch a new component of our dashboard that goes beyond just blocking and analyzing crawls. Site owners will have the ability to set a price for their site, or sections of their site, and to then charge model providers based on their scans and the price you have set. We’ll handle the rest so that you can focus on creating great content for your audience.
The fastest way to get ready to capture value through this new component is to make sure your sites use Cloudflare’s network. We plan to invite sites to participate in the beta based on the date they first joined Cloudflare. Interested in being notified when this is available? Let us know here.
Introducing Ephemeral IDs: a new tool for fraud detection
Post Syndicated from Oliver Payne original https://blog.cloudflare.com/turnstile-ephemeral-ids-for-fraud-detection
In the early days of the Internet, a single IP address was a reliable indicator of a single user. However, today’s Internet is more complex. Shared IP addresses are now common, with users connecting via mobile IP address pools, VPNs, or behind CGNAT (Carrier Grade Network Address Translation). This makes relying on IP addresses alone a weak method to combat modern threats like automated attacks and fraudulent activity. Additionally, many Internet users have no option but to use an IP address which they don’t have sole control over, and as such, should not be penalized for that.
At Cloudflare, we are solving this complexity with Turnstile, our CAPTCHA alternative. And now, we’re taking the next step in advancing security with Ephemeral IDs, a new feature that generates a unique short-lived ID, without relying on any network-level information.
When a website visitor interacts with Turnstile, we now calculate an Ephemeral ID that can link behavior to a specific client instead of an IP address. This means that even when attackers rotate through large pools of IP addresses, we can still identify and block malicious actions. For example, in attacks like credential stuffing or account signups, where fraudsters attempt to disguise themselves using different IP addresses, Ephemeral IDs allow us to detect abuse patterns more accurately beyond just determining whether the visitor is a human or a bot. Multiple fraudulent actions from the same client are grouped together, improving our detection rate while reducing false positives.
How Ephemeral IDs work
Turnstile detects bots by analyzing browser attributes and signals. Using these aggregated client-side signals, we generate a short-lived Ephemeral ID without setting any cookies or using similar client-side storage. These IDs are intentionally not 100% unique and have a brief lifespan, making them highly effective in identifying patterns of fraud and abuse, without compromising user privacy.
When the same visitor interacts with Turnstile widgets from different Cloudflare customers, they receive different Ephemeral IDs for each one. Additionally, because these IDs change frequently, they cannot be used to track a single visitor over multiple days.
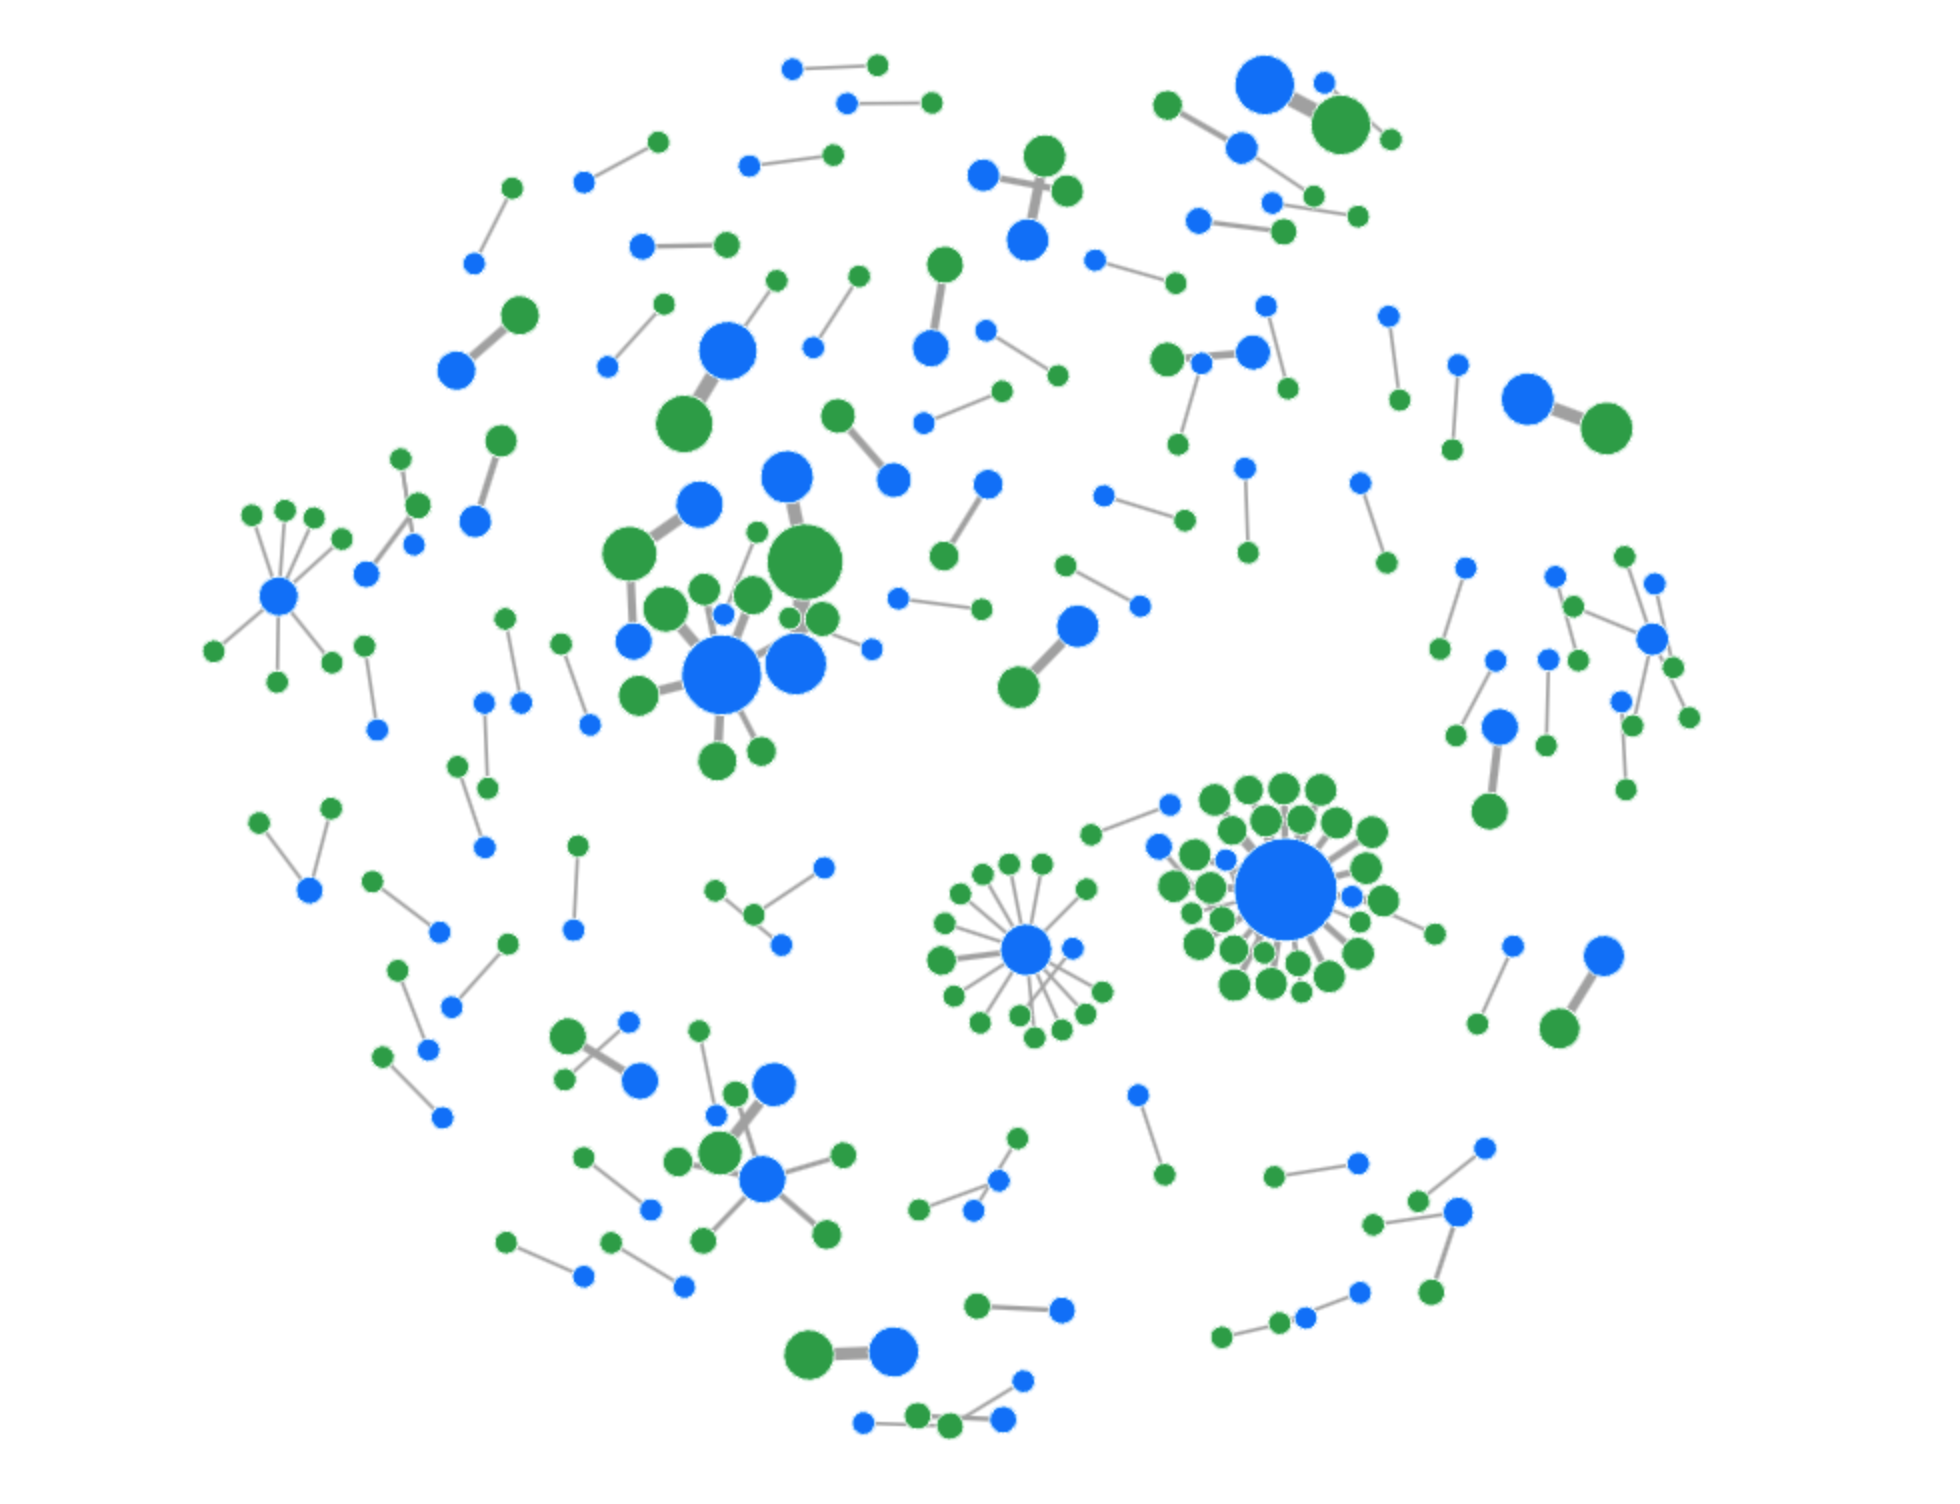
Blue: A single IP address | Green: A single Ephemeral ID
The bigger the node, the more frequently seen that ID or IP address was in our dataset.
The graphic above illustrates the complex reality of the modern Internet, where the relationship between clients and IP addresses is far from a simple one-to-one mapping. While some straightforward mappings still exist, they are no longer the norm.
During a period where a site or service is under attack, we observe a “nest” of highly correlated Ephemeral IDs. In the example below, the correlation is based on both Ephemeral ID and IP address.
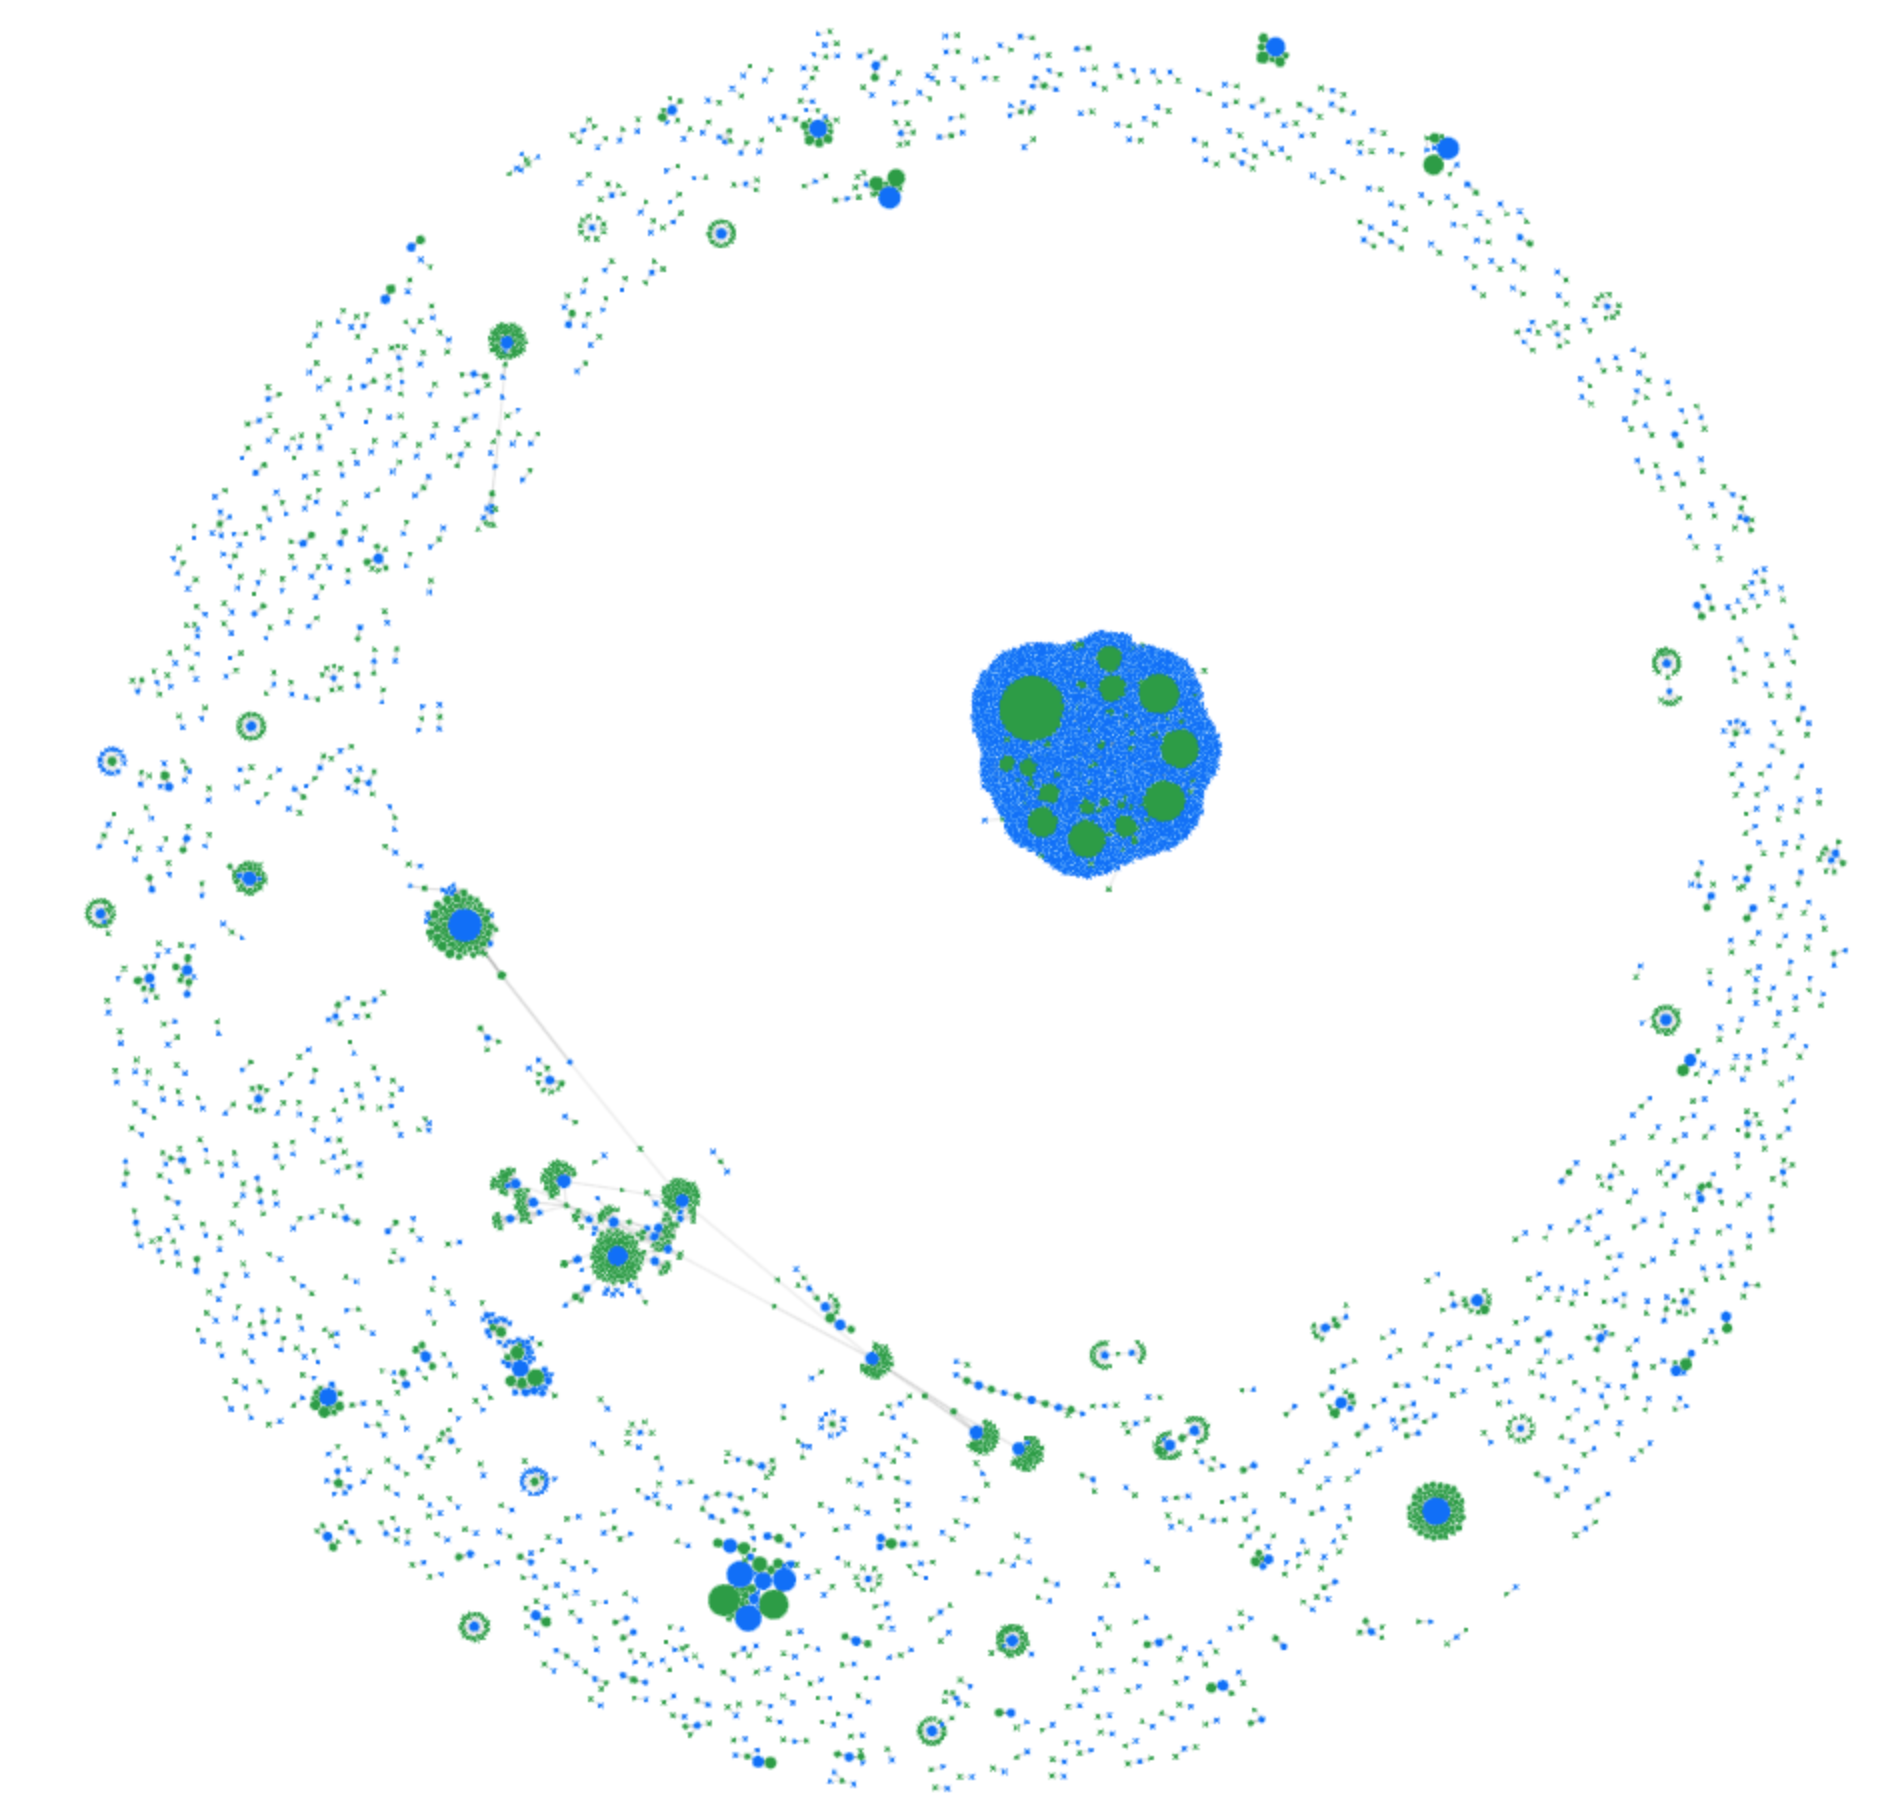
Nest in the center of the diagram visualizes thousands of IP addresses (blue) which are correlated by the commonly identified Ephemeral IDs (green). The bigger the node, the more frequently seen that ID or IP address was in our dataset.
This is real-world data showing fraudulent activity on one of Cloudflare’s public-facing forms. Even with access to a broad range of IP addresses, attackers struggle to completely disguise their requests because Ephemeral IDs are generated based on patterns beyond IP addresses. This means that even if they rotate addresses, the underlying client characteristics are still detected, making it harder for them to evade our security measures. This makes it easier for us to group these requests and apply appropriate business logic, whether that means discarding the requests, requiring further validation, enforcing multi-factor authentication (MFA), or other actions.
This new client identification technology seamlessly integrates into the broader advancements we’ve made to Turnstile over the past year. Whether you’re protecting login forms, signup pages, or high value transactions, you’ll immediately benefit from this extra layer of abuse detection without needing to change a single line of code. We’ll take care of all the heavy lifting and analysis behind the scenes, and our system will continue to improve its accuracy and effectiveness over time.
What does this mean for you? Starting today, Turnstile will go beyond just identifying bots. All websites protected by Turnstile will automatically benefit from the integration of Ephemeral IDs into our detection logic. This means we can more effectively identify and penalize offending clients without impacting other users on the same network, or IP address, improving security and user experience for everyone.
Ephemeral IDs in action
Everyone benefits from the addition of Ephemeral IDs to the Challenge Platform, but for those who want to use it beyond that, the Ephemeral ID is available through the Turnstile siteverify response. A practical use case for Ephemeral IDs is preventing fraudulent account signups. Imagine a bad actor, a real person using a real device, creating hundreds of fake accounts while rotating IP addresses to avoid detection. By ingesting Ephemeral IDs and logging them alongside your account creation logs, you can set up alerts based on account creation thresholds in real-time or retroactively investigate suspicious activity. Even though Ephemeral IDs are short-lived and may have changed by the time an investigation begins, they still provide valuable insights through aggregate analysis, and provide an extra dimension to identify fraud and abuse.
For our Turnstile Enterprise and Bot Management Enterprise customers, you now have the option to access Ephemeral IDs directly through the Turnstile siteverify response. Get in touch with your Account Executive to enable it on your account.
Below is an example of siteverify response for those who have enabled Ephemeral IDs.
curl 'https://challenges.cloudflare.com/turnstile/v0/siteverify' --data 'secret=verysecret&response=<RESPONSE>'{
"success": true,
"error-codes": [],
"challenge_ts": "2024-09-10T17:29:00.463Z",
"hostname": "example.com",
"metadata": {
"ephemeral_id": "x:9f78e0ed210960d7693b167e"
}
}
What’s next for Turnstile?
We launched Turnstile with a bold mission: to redefine CAPTCHAs with a frictionless, privacy-first solution that eliminates the annoyance of picking puzzles, selecting stoplights, and clicking crosswalks to prove our humanity. It’s incredible to think that Turnstile has been generally available for a whole year now! During this time, it has blocked over one trillion bots, and is actively protecting more than 350,000 domains worldwide.
As we celebrate Turnstile’s second birthday, we’re proud of the progress we’ve made and thrilled to introduce our latest innovations. While Ephemeral IDs represent the newest evolution of Turnstile, they’re part of our ongoing commitment to continuous improvement. Over the past year, we’ve also introduced a Cloudflare Pages Plugin and partnered with Google Firebase, ensuring that developers have easy access to Turnstile.
Earlier this year, we also launched Pre-Clearance for Turnstile, integrating it with Cloudflare WAF’s Challenge action, making it easier for customers to use Cloudflare’s Application Security products together. If you want to learn more about how to use Turnstile with Cloudflare’s Bot Management and WAF in more detail, check it out here!
We’re incredibly excited about what’s ahead. The introduction of Ephemeral IDs is just one of many innovations on the horizon. We’re committed to making the Internet a safer, more private place for everyone, eliminating the need for frustrating CAPTCHA puzzles while keeping security our top priority. And with our free tier remaining open and unlimited for all, there’s no barrier to getting started with Turnstile today.
Join us in revolutionizing online security – get started with Turnstile now or dive straight into our how-to guides. Let’s help make the Internet a better place, together!
Network performance update: Birthday Week 2024
Post Syndicated from Emily Music original https://blog.cloudflare.com/network-performance-update-birthday-week-2024
When it comes to the Internet, everyone wants to be the fastest. At Cloudflare, we’re no different. We want to be the fastest network in the world, and are constantly working towards that goal. Since June 2021, we’ve been measuring and ranking our network performance against the top global networks. We use this data to improve our performance, and to share the results of those initiatives.
In this post, we’re going to share with you how our network performance has changed since our last post in March 2024, and discuss the tools and processes we are using to assess network performance.
Digging into the data
Cloudflare has been measuring network performance across these top networks from the top 1,000 ISPs by estimated population (according to the Asia Pacific Network Information Centre (APNIC)), and optimizing our network for ISPs and countries where we see opportunities to improve. For performance benchmarking, we look at TCP connection time. This is the time it takes an end user to connect to the website or endpoint they are trying to reach. We chose this metric to show how our network helps make your websites faster by serving your traffic where your customers are. Back in June 2021, Cloudflare was ranked #1 in 33% of the networks.
As of September 2024, examining 95th percentile (p95) TCP connect times measured from September 4 to September 19, Cloudflare is the #1 provider in 44% of the top 1000 networks:
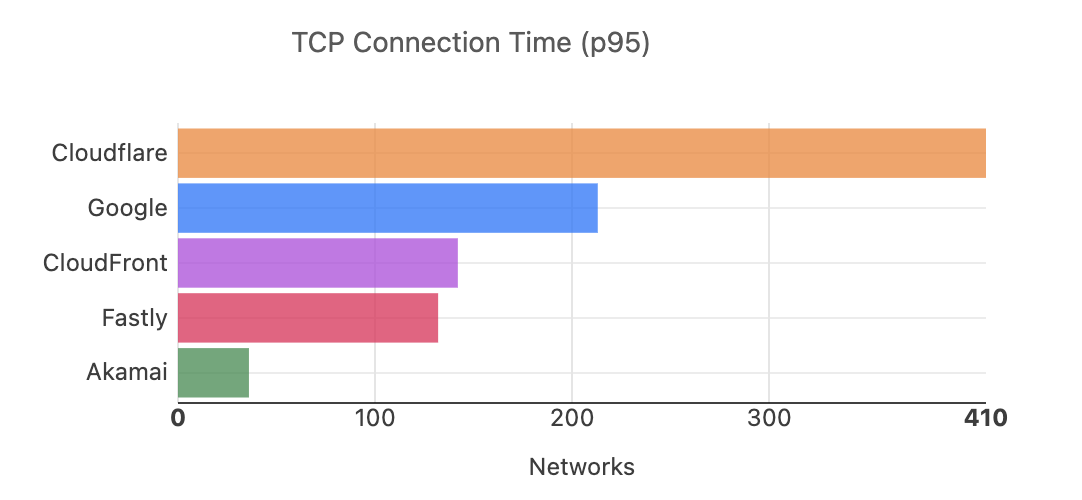
This graph shows that we are fastest in 410 networks, but that would only make us the fastest in 41% of the top 1,000. To make sure we’re looking at the networks that eyeballs connect from, we exclude networks like transit networks that aren’t last-mile ISPs. That brings the number of measured networks to 932, which makes us fastest in 44% of ISPs.
Now let’s take a look at the fastest provider by country. The map below shows the top network by 95th percentile TCP connection time, and Cloudflare is fastest in many countries. For those where we weren’t, we were within a few milliseconds of our closest competitor.
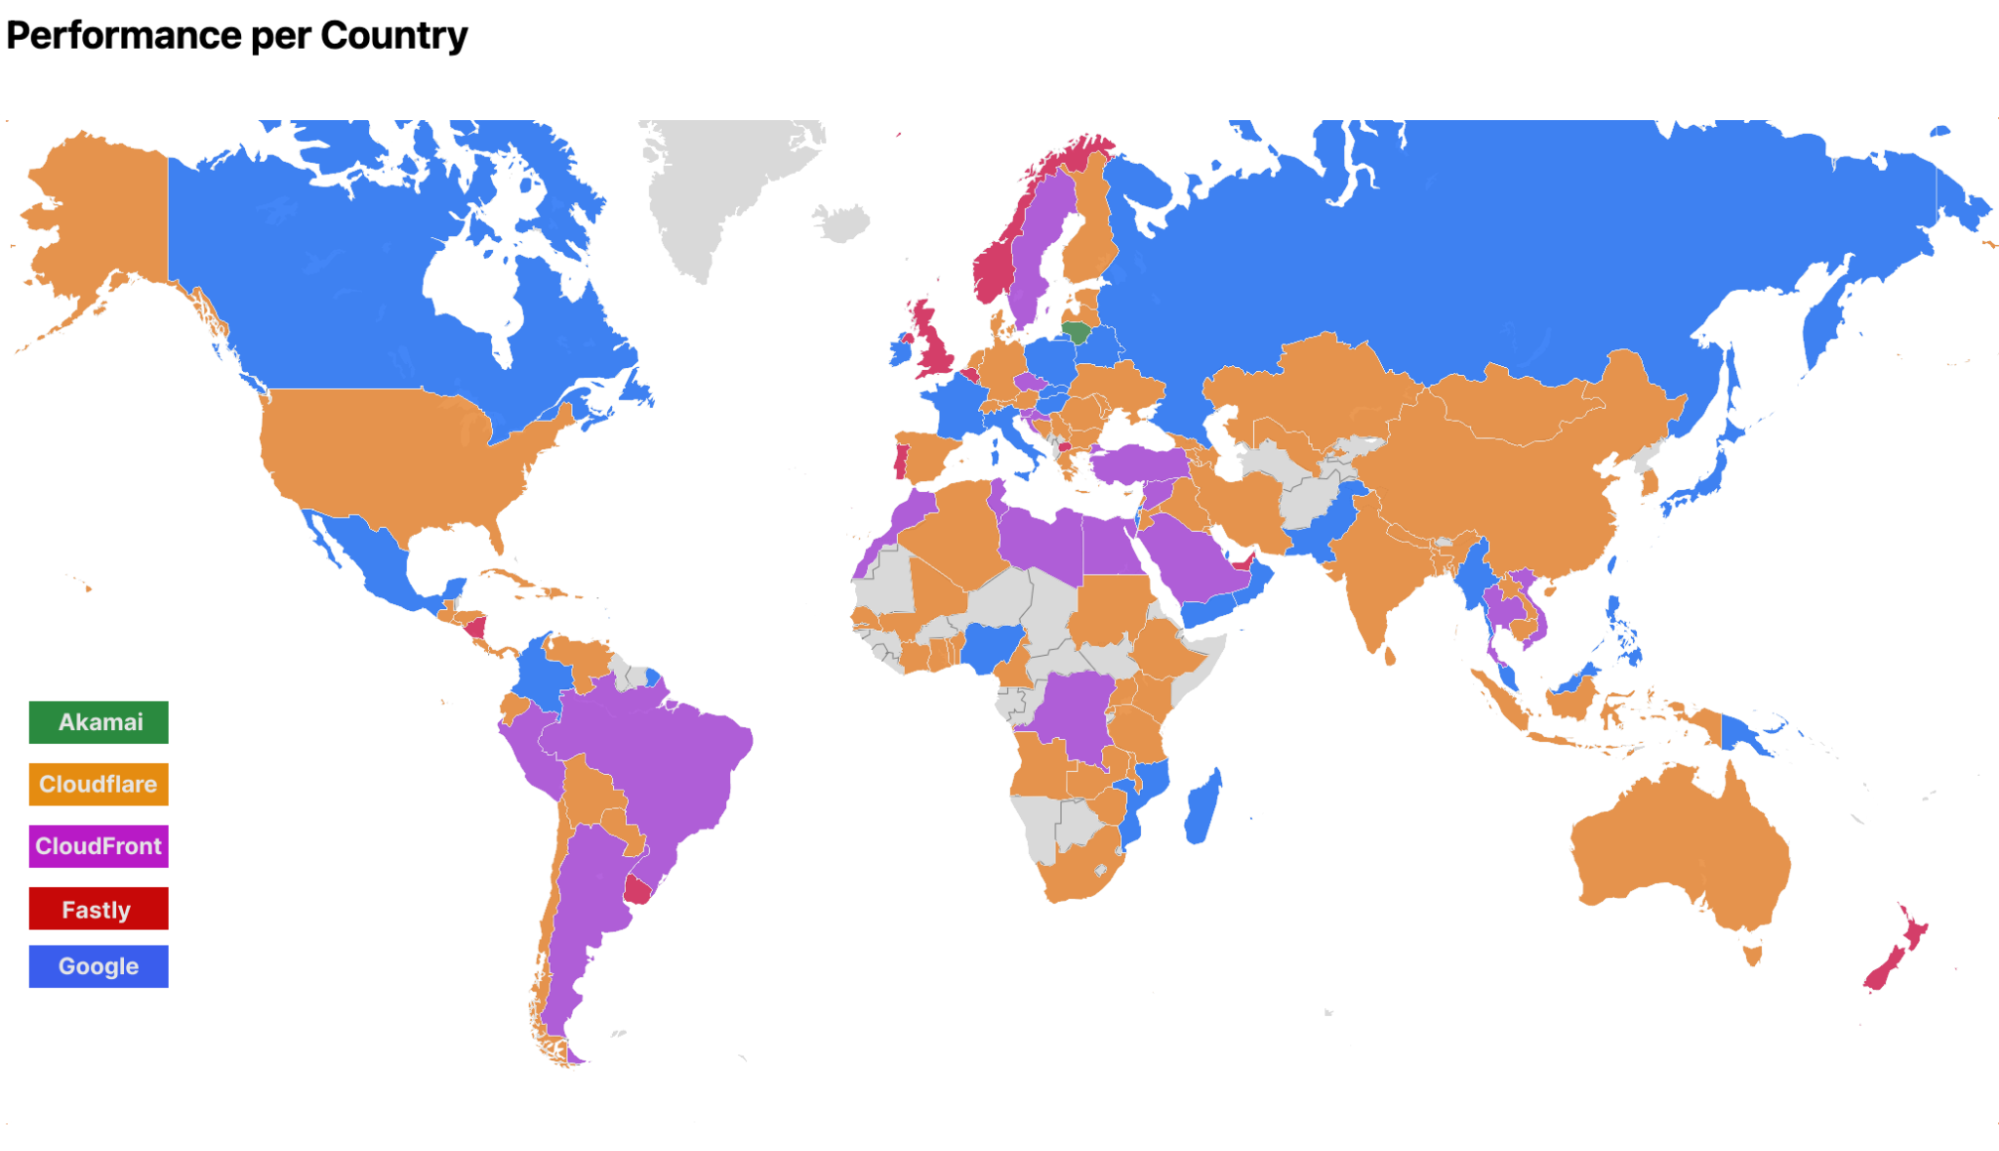
This color coding is generated by grouping all the measurements we generate by which country the measurement originates from, and then looking at the 95th percentile measurements for each provider to see who is the fastest. This is in contrast to how we measure who is fastest in individual networks, which involves grouping the measurements by ISP and measuring which provider is fastest. Cloudflare is still the fastest provider in 44% of the measured networks, which is consistent with our March report. Cloudflare is also the fastest in many countries, but the map is less orange than it was when we published our measurements from March 2024:
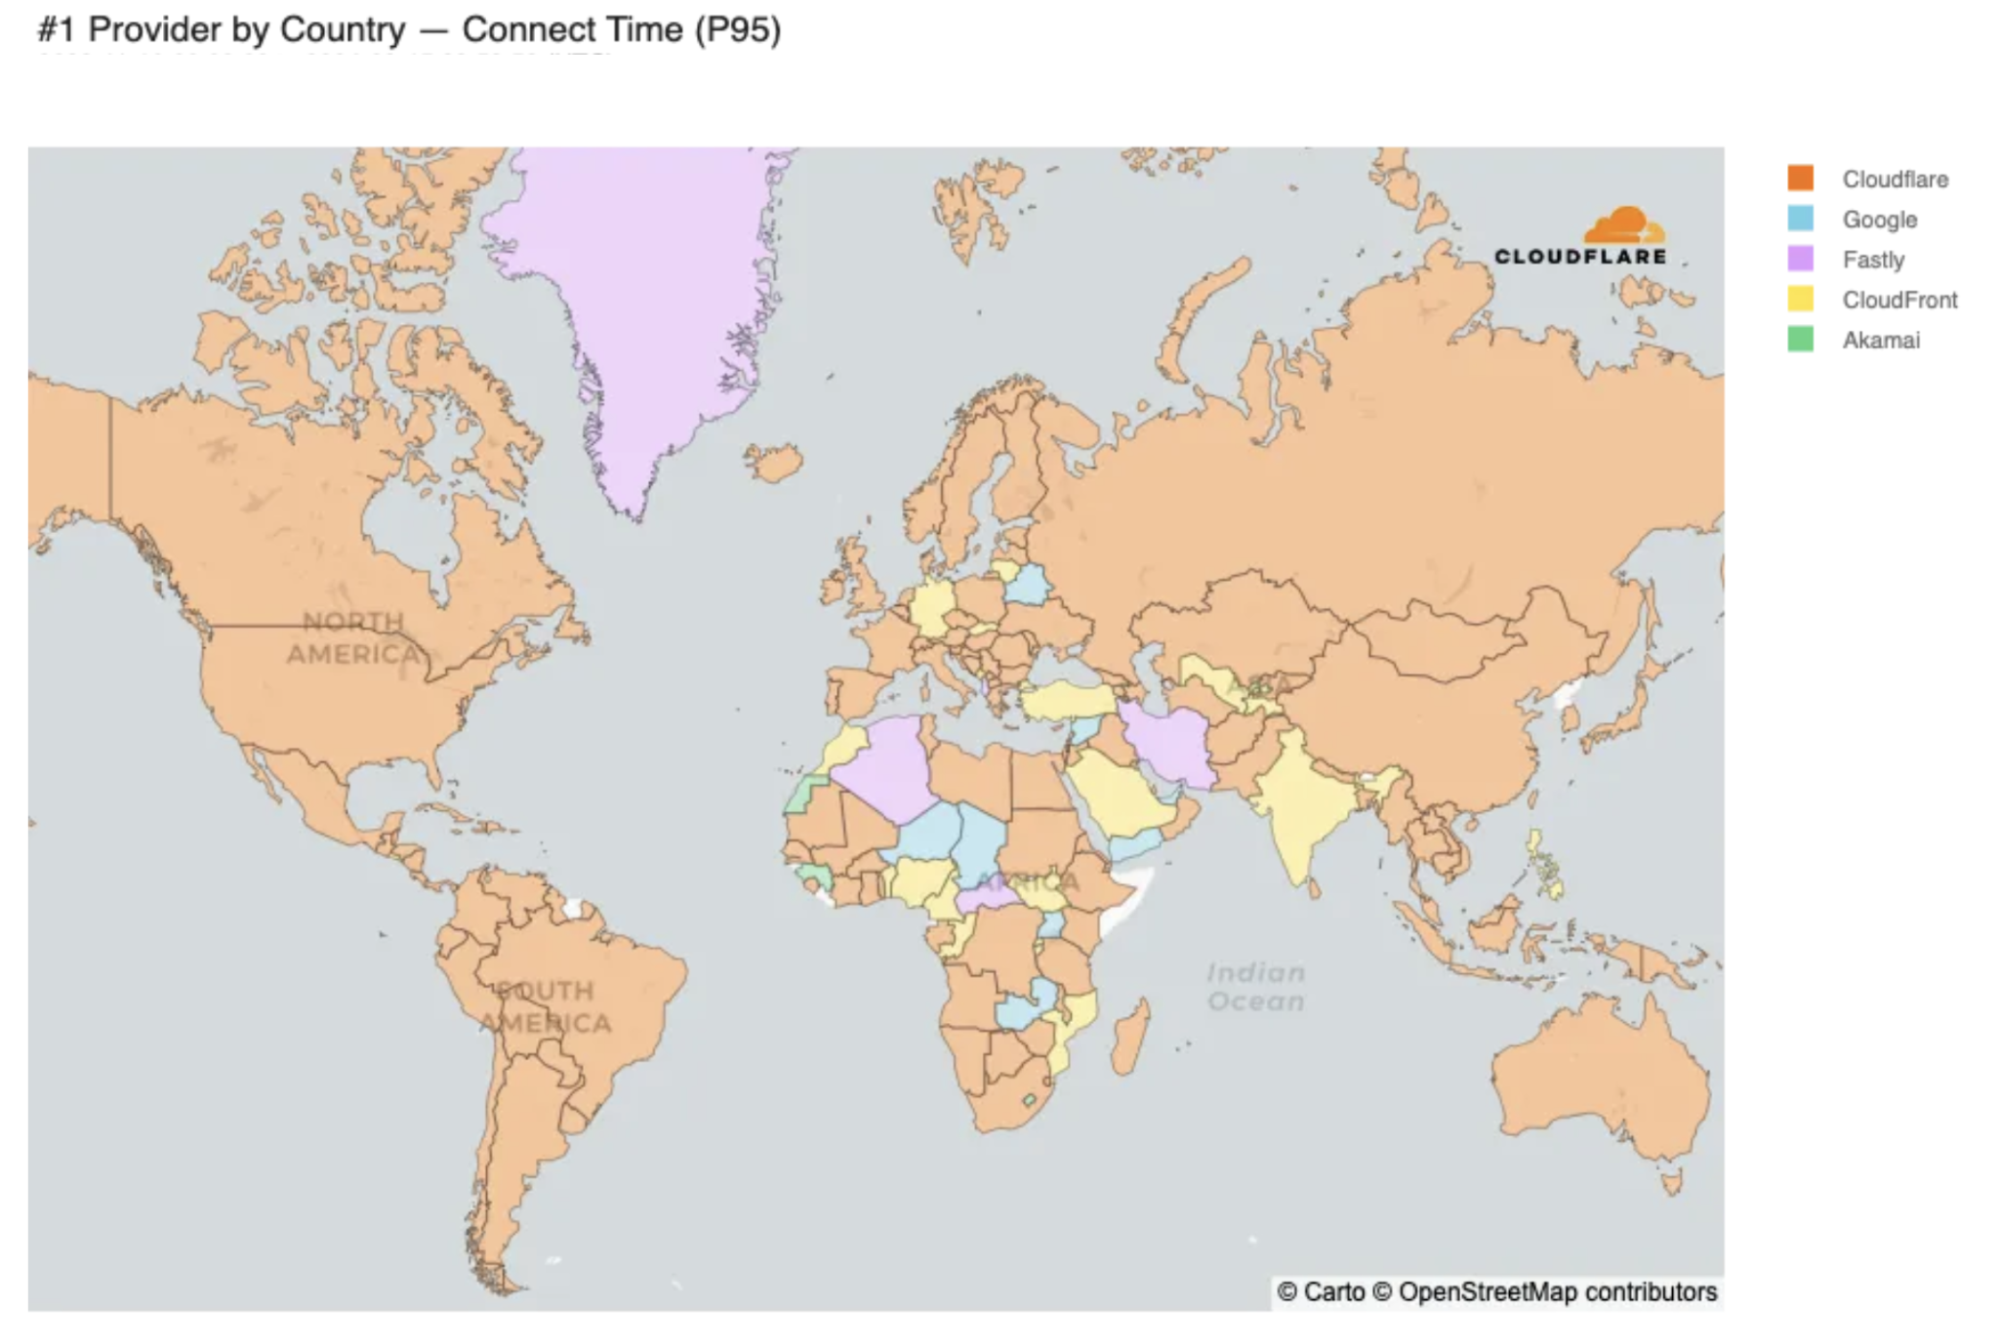
This can be explained by the fact that the fastest provider in a country is often determined by latency differences so small it is often less than 5% faster than the second-fastest provider. As an example, let’s take a look at India, a country where we are now the fastest:
India performance by provider
|
Rank |
Entity |
95th percentile TCP Connect (ms) |
Difference from #1 |
|---|---|---|---|
|
1 |
Cloudflare |
290 ms |
– |
|
2 |
|
291 ms |
+0.28% (+0.81 ms) |
|
3 |
CloudFront |
304 ms |
+4.61% (+13 ms) |
|
4 |
Fastly |
325 ms |
+12% (+35 ms) |
|
5 |
Akamai |
373 ms |
+29% (+83 ms) |
In India, we are the fastest network, but we are beating the runner-up by less than a millisecond, which shakes out to less than 1% difference between us and the number two! The competition for the number one spot in many countries is fierce and sometimes can be determined by what days you’re looking at the data, because variance in connectivity or last-mile outages can materially impact this data.
For example, on September 17, there was an outage on a major network in India, which impacted many users’ ability to access the Internet. People using this network were significantly impacted in their ability to connect to Cloudflare, and you can actually see that impact in the data. Here’s what the data looked like on the day of the outage, as we dropped from the number one spot that day:
India performance by provider
|
Rank |
Entity |
95th percentile TCP Connect (ms) |
Difference from #1 |
|---|---|---|---|
|
1 |
|
219 ms |
– |
|
2 |
CloudFront |
230 ms |
+5% (+11 ms) |
|
3 |
Cloudflare |
236 ms |
+7.47% (+16 ms) |
|
4 |
Fastly |
261 ms |
+19% (+41 ms) |
|
5 |
Akamai |
286 ms |
+30% (+67 ms) |
We were impacted more than other providers here because our automated traffic management systems detected the high packet loss as a result of the outage and aggressively moved all of our traffic away from the impacted provider. After review internally, we have identified opportunities to improve our traffic management to be more fine-grained in our approach to outages of this type, which would help us continue to be fast despite changes in the surrounding ecosystem. These unplanned occurrences can happen to any network, but these events also provide us opportunities to improve and mitigate the randomness we see on the Internet.
The phenomenon of providers having fluctuating latencies can also work against us. Consider Poland, a country where we were the fastest provider in March, but are no longer the fastest provider today. Digging into the data a bit more, we can see that even though we are no longer the fastest, we’re slower by less than a millisecond, giving us confidence that our architecture is optimized for performance in the region:
Poland performance by provider
|
Rank |
Entity |
95th percentile TCP Connect (ms) |
Difference from #1 |
|---|---|---|---|
|
1 |
|
246 ms |
– |
|
2 |
Cloudflare |
246 ms |
+0.15% (+0.36 ms) |
|
3 |
CloudFront |
250 ms |
+1.7% (+4.17 ms) |
|
4 |
Akamai |
272 ms |
+11% (+26 ms) |
|
5 |
Fastly |
295 ms |
+20% (+50 ms) |
These nuances in the data can make us look slower in more countries than we actually are. From a numbers’ perspective we’re neck-and-neck with our competitors and still fastest in the most networks around the world. Going forward, we’re going to take a longer look at how we’re visualizing our network performance to paint a clearer picture for you around performance. But let’s go into more about how we actually get the underlying data we use to measure ourselves.
How we measure performance
When you see a Cloudflare-branded error page, something interesting happens behind the scenes. Every time one of these error pages is displayed, Cloudflare gathers Real User Measurements (RUM) by fetching a tiny file from various networks, including Cloudflare, Akamai, Amazon CloudFront, Fastly, and Google Cloud CDN. Your browser sends back performance data from the end-user’s perspective, helping us get a clear view of how these different networks stack up in terms of speed. The main goal? Figure out where we’re fast, and more importantly, where we can make Cloudflare even faster. If you’re curious about the details, the original Speed Week blog post dives deeper into the methodology.
Using this RUM data, we track key performance metrics such as TCP Connection Time, Time to First Byte (TTFB), and Time to Last Byte (TTLB) for Cloudflare and the other networks.
Starting from March, we fixed the list of networks we look at to be the top 1000 networks by estimated population as determined by APNIC, and we removed networks that weren’t last-mile ISPs. This change makes our measurements and reporting more consistent because we look at the same set of networks for every reporting cycle.
How does Cloudflare use this data?
Cloudflare uses this data to improve our network performance in lagging regions. For example, in 2022 we recognized that performance on a network in Finland was not as fast as some comparable regions. Users were taking 300+ ms to connect to Cloudflare at the 95th percentile:
Performance for Finland network
|
Rank |
Entity |
95th percentile TCP Connect (ms) |
Difference from #1 |
|---|---|---|---|
|
1 |
Fastly |
15 ms |
– |
|
2 |
CloudFront |
19 ms |
+19% (+3 ms) |
|
3 |
Akamai |
20 ms |
+28% (+4.3 ms) |
|
4 |
|
72 ms |
+363% (+56 ms) |
|
5 |
Cloudflare |
368 ms |
+2378% (+353 ms) |
After investigating, we recognized that one major network in Finland was seeing high latency due to issues resulting from congestion. Simply put, we were using all the capacity we had. We immediately planned an expansion, and within two weeks of that expansion completion, our latency decreased, and we became the fastest provider in the region, as you can see in the map above.
We are constantly improving our network and infrastructure to better serve our customers. Data like this helps us identify where we can be most impactful, and improve service for our customers.
What’s next
We’re sharing our updates on our journey to become as fast as we can be everywhere so that you can see what goes into running the fastest network in the world. From here, our plan is the same as always: identify where we’re slower, fix it, and then tell you how we’ve gotten faster.
Making zone management more efficient with batch DNS record updates
Post Syndicated from Alex Fattouche original https://blog.cloudflare.com/batched-dns-changes
Customers that use Cloudflare to manage their DNS often need to create a whole batch of records, enable proxying on many records, update many records to point to a new target at the same time, or even delete all of their records. Historically, customers had to resort to bespoke scripts to make these changes, which came with their own set of issues. In response to customer demand, we are excited to announce support for batched API calls to the DNS records API starting today. This lets customers make large changes to their zones much more efficiently than before. Whether sending a POST, PUT, PATCH or DELETE, users can now execute these four different HTTP methods, and multiple HTTP requests all at the same time.
Efficient zone management matters
DNS records are an essential part of most web applications and websites, and they serve many different purposes. The most common use case for a DNS record is to have a hostname point to an IPv4 address, this is called an A record:
example.com 59 IN A 198.51.100.0
blog.example.com 59 IN A 198.51.100.1
ask.example.com 59 IN A 198.51.100.2
In its most simple form, this enables Internet users to connect to websites without needing to memorize their IP address.
Often, our customers need to be able to do things like create a whole batch of records, or enable proxying on many records, or update many records to point to a new target at the same time, or even delete all of their records. Unfortunately, for most of these cases, we were asking customers to write their own custom scripts or programs to do these tasks for them, a number of which are open sourced and whose content has not been checked by us. These scripts are often used to avoid needing to repeatedly make the same API calls manually. This takes time, not only for the development of the scripts, but also to simply execute all the API calls, not to mention it can leave the zone in a bad state if some changes fail while others succeed.
Introducing /batch
Starting today, everyone with a Cloudflare zone will have access to this endpoint, with free tier customers getting access to 200 changes in one batch, and paid plans getting access to 3,500 changes in one batch. We have successfully tested up to 100,000 changes in one call. The API is simple, expecting a POST request to be made to the new API endpoint /dns_records/batch, which passes in a JSON object in the body in the format:
{
    deletes:[]Record
    patches:[]Record
    puts:[]Record
    posts:[]Record
}
Each list of records []Record will follow the same requirements as the regular API, except that the record ID on deletes, patches, and puts will be required within the Record object itself. Here is a simple example:
{
    "deletes": [
        {
            "id": "143004ef463b464a504bde5a5be9f94a"
        },
        {
            "id": "165e9ef6f325460c9ca0eca6170a7a23"
        }
    ],
    "patches": [
        {
            "id": "16ac0161141a4e62a79c50e0341de5c6",
            "content": "192.0.2.45"
        },
        {
            "id": "6c929ea329514731bcd8384dd05e3a55",
            "name": "update.example.com",
            "proxied": true
        }
    ],
    "puts": [
        {
            "id": "ee93eec55e9e45f4ae3cb6941ffd6064",
            "content": "192.0.2.50",
            "name": "no-change.example.com",
            "proxied": false,
            "ttl:": 1
        },
        {
            "id": "eab237b5a67e41319159660bc6cfd80b",
            "content": "192.0.2.45",
            "name": "no-change.example.com",
            "proxied": false,
            "ttl:": 3000
        }
    ],
    "posts": [
        {
            "name": "@",
            "type": "A",
            "content": "192.0.2.45",
            "proxied": false,
            "ttl": 3000
        },
        {
            "name": "a.example.com",
            "type": "A",
            "content": "192.0.2.45",
            "proxied": true
        }
    ]
}
Our API will then parse this and execute these calls in the following order:
-
deletes
-
patches
-
puts
-
posts
Each of these respective lists will be executed in the order given. This ordering system is important because it removes the need for our clients to worry about conflicts, such as if they need to create a CNAME on the same hostname as a to-be-deleted A record, which is not allowed in RFC 1912. In the event that any of these individual actions fail, the entire API call will fail and return the first error it sees. The batch request will also be executed inside a single database transaction, which will roll back in the event of failure.
After the batch request has been successfully executed in our database, we then propagate the changes to our edge via Quicksilver, our distributed KV store. Each of the individual record changes inside the batch request is treated as a single key-value pair, and database transactions are not supported. As such, we cannot guarantee that the propagation to our edge servers will be atomic. For example, if replacing a delegation with an A record, some resolvers may see the NS record removed before the A record is added.
The response will follow the same format as the request. Patches and puts that result in no changes will be placed at the end of their respective lists.
We are also introducing some new changes to the Cloudflare dashboard, allowing users to select multiple records and subsequently:
-
Delete all selected records
-
Change the proxy status of all selected records
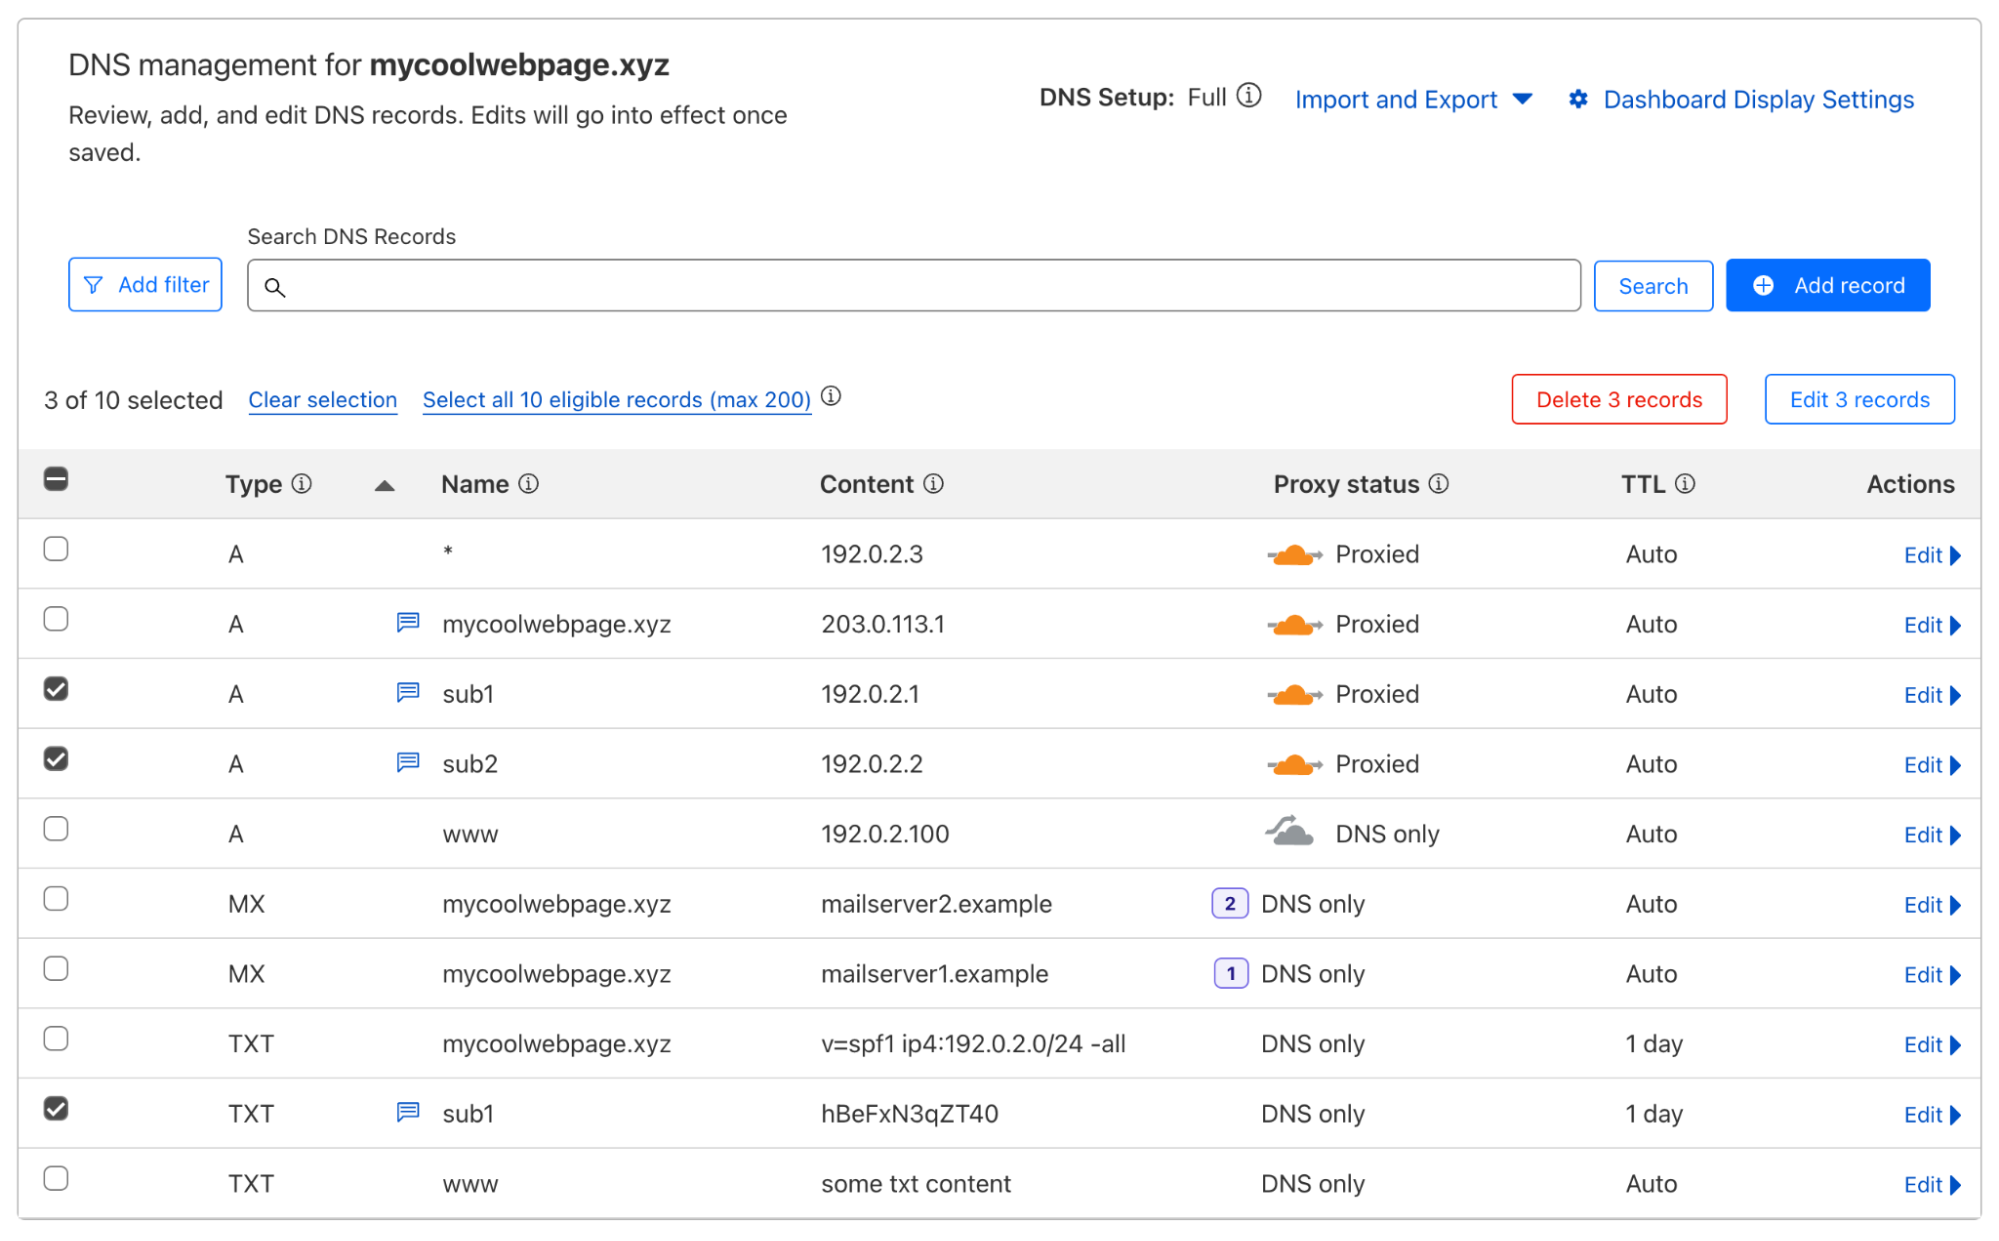
We plan to continue improving the dashboard to support more batch actions based on your feedback.
The journey
Although at the surface, this batch endpoint may seem like a fairly simple change, behind the scenes it is the culmination of a multi-year, multi-team effort. Over the past several years, we have been working hard to improve the DNS pipeline that takes our customers’ records and pushes them to Quicksilver, our distributed database. As part of this effort, we have been improving our DNS Records API to reduce the overall latency. The DNS Records API is Cloudflare’s most used API externally, serving twice as many requests as any other API at peak. In addition, the DNS Records API supports over 20 internal services, many of which touch very important areas such as DNSSEC, TLS, Email, Tunnels, Workers, Spectrum, and R2 storage. Therefore, it was important to build something that scales.
To improve API performance, we first needed to understand the complexities of the entire stack. At Cloudflare, we use Jaeger tracing to debug our systems. It gives us granular insights into a sample of requests that are coming into our APIs. When looking at API request latency, the span that stood out was the time spent on each individual database lookup. The latency here can vary anywhere from ~1ms to ~5ms.


Jaeger trace showing variable database latency
Given this variability in database query latency, we wanted to understand exactly what was going on within each DNS Records API request. When we first started on this journey, the breakdown of database lookups for each action was as follows:
|
Action |
Database Queries |
Reason |
|---|---|---|
|
POST |
2 |
One to write and one to read the new record. |
|
PUT |
3 |
One to collect, one to write, and one to read back the new record. |
|
PATCH |
3 |
One to collect, one to write, and one to read back the new record. |
|
DELETE |
2 |
One to read and one to delete. |
The reason we needed to read the newly created records on POST, PUT, and PATCH was because the record contains information filled in by the database which we cannot infer in the API.
Let’s imagine that a customer needed to edit 1,000 records. If each database lookup took 3ms to complete, that was 3ms * 3 lookups * 1,000 records = 9 seconds spent on database queries alone, not taking into account the round trip time to and from our API or any other processing latency. It’s clear that we needed to reduce the number of overall queries and ideally minimize per query latency variation. Let’s tackle the variation in latency first.
Each of these calls is not a simple INSERT, UPDATE, or DELETE, because we have functions wrapping these database calls for sanitization purposes. In order to understand the variable latency, we enlisted the help of PostgreSQL’s “auto_explain”. This module gives a breakdown of execution times for each statement without needing to EXPLAIN each one by hand. We used the following settings:
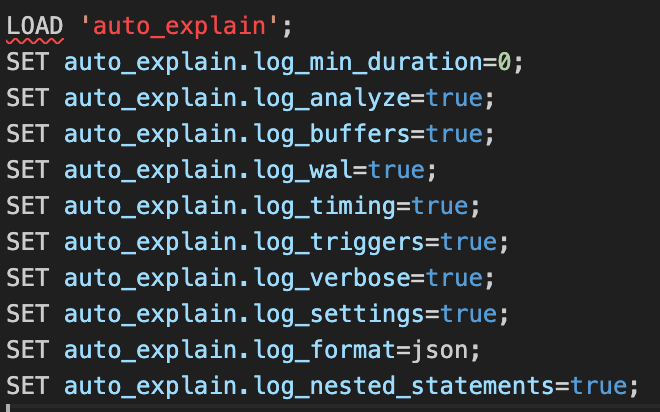
A handful of queries showed durations like the one below, which took an order of magnitude longer than other queries.

We noticed that in several locations we were doing queries like:
IF (EXISTS (SELECT id FROM table WHERE row_hash = __new_row_hash))
If you are trying to insert into very large zones, such queries could mean even longer database query times, potentially explaining the discrepancy between 1ms and 5ms in our tracing images above. Upon further investigation, we already had a unique index on that exact hash. Unique indexes in PostgreSQL enforce the uniqueness of one or more column values, which means we can safely remove those existence checks without risk of inserting duplicate rows.
The next task was to introduce database batching into our DNS Records API. In any API, external calls such as SQL queries are going to add substantial latency to the request. Database batching allows the DNS Records API to execute multiple SQL queries within one single network call, subsequently lowering the number of database round trips our system needs to make.
According to the table above, each database write also corresponded to a read after it had completed the query. This was needed to collect information like creation/modification timestamps and new IDs. To improve this, we tweaked our database functions to now return the newly created DNS record itself, removing a full round trip to the database. Here is the updated table:
|
Action |
Database Queries |
Reason |
|---|---|---|
|
POST |
1 |
One to write |
|
PUT |
2 |
One to read, one to write. |
|
PATCH |
2 |
One to read, one to write. |
|
DELETE |
2 |
One to read, one to delete. |
We have room for improvement here, however we cannot easily reduce this further due to some restrictions around auditing and other sanitization logic.
Results:
|
Action |
Average database time before |
Average database time after |
Percentage Decrease |
|---|---|---|---|
|
POST |
3.38ms |
0.967ms |
71.4% |
|
PUT |
4.47ms |
2.31ms |
48.4% |
|
PATCH |
4.41ms |
2.24ms |
49.3% |
|
DELETE |
1.21ms |
1.21ms |
0% |
These are some pretty good improvements! Not only did we reduce the API latency, we also reduced the database query load, benefiting other systems as well.
Weren’t we talking about batching?
I previously mentioned that the /batch endpoint is fully atomic, making use of a single database transaction. However, a single transaction may still require multiple database network calls, and from the table above, that can add up to a significant amount of time when dealing with large batches. To optimize this, we are making use of pgx/batch, a Golang object that allows us to write and subsequently read multiple queries in a single network call. Here is a high level of how the batch endpoint works:
-
Collect all the records for the PUTs, PATCHes and DELETEs.
-
Apply any per record differences as requested by the PATCHes and PUTs.
-
Format the batch SQL query to include each of the actions.
-
Execute the batch SQL query in the database.
-
Parse each database response and return any errors if needed.
-
Audit each change.
This takes at most only two database calls per batch. One to fetch, and one to write/delete. If the batch contains only POSTs, this will be further reduced to a single database call. Given all of this, we should expect to see a significant improvement in latency when making multiple changes, which we do when observing how these various endpoints perform:
Note: Each of these queries was run from multiple locations around the world and the median of the response times are shown here. The server responding to queries is located in Portland, Oregon, United States. Latencies are subject to change depending on geographical location.
Create only:
|
10 Records |
100 Records |
1,000 Records |
10,000 Records |
|
|---|---|---|---|---|
|
Regular API |
7.55s |
74.23s |
757.32s |
7,877.14s |
|
Batch API – Without database batching |
0.85s |
1.47s |
4.32s |
16.58s |
|
Batch API – with database batching |
0.67s |
1.21s |
3.09s |
10.33s |
Delete only:
|
10 Records |
100 Records |
1,000 Records |
10,000 Records |
|
|---|---|---|---|---|
|
Regular API |
7.28s |
67.35s |
658.11s |
7,471.30s |
|
Batch API – without database batching |
0.79s |
1.32s |
3.18s |
17.49s |
|
Batch API – with database batching |
0.66s |
0.78s |
1.68s |
7.73s |
Create/Update/Delete:
|
10 Records |
100 Records |
1,000 Records |
10,000 Records |
|
|---|---|---|---|---|
|
Regular API |
7.11s |
72.41s |
715.36s |
7,298.17s |
|
Batch API – without database batching |
0.79s |
1.36s |
3.05s |
18.27s |
|
Batch API – with database batching |
0.74s |
1.06s |
2.17s |
8.48s |
Overall Average:
|
10 Records |
100 Records |
1,000 Records |
10,000 Records |
|
|---|---|---|---|---|
|
Regular API |
7.31s |
71.33s |
710.26s |
7,548.87s |
|
Batch API – without database batching |
0.81s |
1.38s |
3.51s |
17.44s |
|
Batch API – with database batching |
0.69s |
1.02s |
2.31s |
8.85s |
We can see that on average, the new batching API is significantly faster than the regular API trying to do the same actions, and it’s also nearly twice as fast as the batching API without batched database calls. We can see that at 10,000 records, the batching API is a staggering 850x faster than the regular API. As mentioned above, these numbers are likely to change for a number of different reasons, but it’s clear that making several round trips to and from the API adds substantial latency, regardless of the region.
Batch overload
Making our API faster is awesome, but we don’t operate in an isolated environment. Each of these records needs to be processed and pushed to Quicksilver, our distributed database. If we have customers creating tens of thousands of records every 10 seconds, we need to be able to handle this downstream so that we don’t overwhelm our system. In a May 2022 blog post titled How we improved DNS record build speed by more than 4,000x, I noted that:
We plan to introduce a batching system that will collect record changes into groups to minimize the number of queries we make to our database and Quicksilver.
This task has since been completed, and our propagation pipeline is now able to batch thousands of record changes into a single database query which can then be published to Quicksilver in order to be propagated to our global network.
Next steps
We have a couple more improvements we may want to bring into the API. We also intend to improve the UI to bring more usability improvements to the dashboard to more easily manage zones. We would love to hear your feedback, so please let us know what you think and if you have any suggestions for improvements.
For more details on how to use the new /batch API endpoint, head over to our developer documentation and API reference.
Expanding the Security Horizon: Introducing Rapid7 MDR for the Extended Ecosystem
Post Syndicated from Mikayla Wyman original https://blog.rapid7.com/2024/09/23/expanding-the-security-horizon-introducing-rapid7-mdr-for-the-extended-ecosystem/
As the cybersecurity landscape gets more complex, the stakes for keeping organizations safe have never been higher. Security teams are tasked with keeping ahead of new ransomware groups, rapidly evolving adversary tactics, and their dynamic attack surface as their business grows. Security organizations’ scope of responsibility has swelled as their tech ecosystem has sprawled, with the average team now managing 45 security tools in their environment.
Managed detection and response (MDR) services can be a life raft for many teams looking to extend their team with expert support and 24×7 coverage. But traditional MDR needs to evolve to accommodate the widening attack surface and security scope.
Our Rapid7 MXDR service has always been built on InsightIDR, our native SIEM and XDR technology, operationalizing telemetry across the customer environment —endpoint, cloud, identity, and network. This multi-layered approach is critical in today’s environment, where advanced threats require rapid identification and response across the entire ecosystem.
Introducing: MDR for the extended ecosystem
We are proud to announce the launch of Rapid7 MDR for the extended ecosystem, extending our MXDR service to triage, investigate, and respond to alerts from third-party tools already in use within your organization. These investments will extend Rapid7’s foundational native telemetry, layering alerts from customers’ third-party point solutions like cloud service providers (CSPs), identity and access management (IAM) platforms, and endpoint protection platforms (EPPs).
This initial release will bring support for major EPPs such as Microsoft Defender for Endpoint, CrowdStrike Falcon, and SentinelOne Singularity, with plans to extend coverage to more third-party tools across cloud, identity, and network in the coming months. By integrating third-party alerts, organizations can now customize their MDR coverage to cover the unique technology environment.
What sets Rapid7 MDR apart: customization, visibility, and Active Response
By extending the Rapid7 SOC’s coverage to include alerts from third parties, we’re bringing comprehensive, robust coverage to our customers through:
- Customization: Integrate your existing tools with Rapid7’s native telemetry to create a customized service that matches your specific environment, tailoring your MDR service to your environment, layering alert data to speed up investigations across multiple layers of your ecosystem.
- Visibility: By synthesizing data from both native and third-party telemetry, we’re bringing complete visibility across endpoints, cloud, identity, and network layers. This eliminates blind spots, helping you detect and respond to abnormal and malicious activity across your entire attack surface.
- Response: By extending the MDR service to detect, triage, and investigate third party event sources, the Rapid7 SOC has more context and information to respond to and contain malicious behavior before it can cause harm to your environment, business, and brand.
“We have been using Rapid7 MDR for our organization’s cyber security needs, and I must say, it has been a game-changer. From the moment we implemented the service, we experienced a significant improvement in our overall security posture and threat detection capabilities.”
The best is yet to come
As we extend our MDR service, we’re excited to partner with you as the command center for your security teams. This extended delivery model brings our MDR and Managed Threat Complete customers the ability to utilize the Rapid7 SOC to triage, investigate, and respond to events happening across supported providers in their wider ecosystem, helping them command their attack surface.
If you’re a Rapid7 MDR customer, reach out to your account team to learn more about our extended coverage. If you’re not a Rapid7 MDR customer yet, request a demo here.
Theodore Roosevelt’s Medal of Honor
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=xALnskXhoS0
[$] Tools for kernel developers
Post Syndicated from corbet original https://lwn.net/Articles/991033/
Konstantin Ryabitsev started a session on development tooling at the 2024
Maintainers Summit by saying that he does not want to be a “wrecking ball”.
If a given workflow is working for people, he does not want to try to force
any sort of change. That said, he has ideas for how he can continue his
work on providing better tooling for the development community.
Hello World #25 out now: Generative AI
Post Syndicated from Meg Wang original https://www.raspberrypi.org/blog/hello-world-25-out-now-generative-ai/
Since they became publicly available at the end of 2022, generative AI tools have been hotly discussed by educators: what role should these tools for generating human-seeming text, images, and other media play in teaching and learning?
Two years later, the one thing most people agree on is that, like it or not, generative AI is here to stay. And as a computing educator, you probably have your learners and colleagues looking to you for guidance about this technology. We’re sharing how educators like you are approaching generative AI in issue 25 of Hello World, out today for free.
Generative AI and teaching
Since our ‘Teaching and AI’ issue a year ago, educators have been making strides grappling with generative AI’s place in their classroom, and with the potential risks to young people. In this issue, you’ll hear from a wide range of educators who are approaching this technology in different ways.
For example:
- Laura Ventura from Gwinnett County Public Schools (GCPS) in Georgia, USA shares how the GCPS team has integrated AI throughout their K–12 curriculum
- Mark Calleja from our team guides you through using the OCEAN prompt process to reliably get the results you want from an LLM
- Kip Glazer, principal at Mountain View High School in California, USA shares a framework for AI implementation aimed at school leaders
- Stefan Seegerer, a researcher and educator in Germany, discusses why unplugged activities help us focus on what’s really important in teaching about AI
This issue also includes practical solutions to problems that are unique to computer science educators:
- Graham Hastings in the UK shares his solution to tricky crocodile clips when working with micro:bits
- Riyad Dhuny shares his case study of home-hosting a learning management system with his students in Mauritius
And there is lots more for you to discover in issue 25.
Whether or not you use generative AI as part of your teaching practice, it’s important for you to be aware of AI technologies and how your young people may be interacting with it. In his article “A problem-first approach to the development of AI systems”, Ben Garside from our team affirms that:
“A big part of our job as educators is to help young people navigate the changing world and prepare them for their futures, and education has an essential role to play in helping people understand AI technologies so that they can avoid the dangers.
Our approach at the Raspberry Pi Foundation is not to focus purely on the threats and dangers, but to teach young people to be critical users of technologies and not passive consumers. […]
Our call to action to educators, carers, and parents is to have conversations with your young people about generative AI. Get to know their opinions on it and how they view its role in their lives, and help them to become critical thinkers when interacting with technology.”
Share your thoughts & subscribe to Hello World
Computing teachers are being asked again to teach something that they didn’t study. With generative AI as with all things computing, we want to support your teaching and share your successes. We hope you enjoy this issue of Hello World, and please get in touch with your article ideas or what you would like to see in the magazine.
- Share your thoughts and ideas about Hello World and the new issue with us on social media by tagging the Hello World Twitter/X or Facebook accounts
- Find out how you can write for the magazine
- Subscribe to Hello World for free to never miss an issue
We’d like to thank Oracle for supporting this issue.
The post Hello World #25 out now: Generative AI appeared first on Raspberry Pi Foundation.
2024-09-23 гласуване за лекции на OpenFest
Post Syndicated from Vasil Kolev original https://vasil.ludost.net/blog/?p=3486
vote.openfest.org, както винаги. Гласуването помага за подреждането на лекциите и понякога за избора им.
(има и моя там, но понеже аз държах на това да не се виждат кои са лекторите, за да се избират лекции на база материала в тях, няма да кажа коя)
(както и че ще я правя тестово в събота в initLab)
Как подкрепя България глухите граждани?
Post Syndicated from original https://www.toest.bg/kak-podkrepya-bulgaria-ghluhite-grazhdani/

През 1958 г. Световната федерация на глухите за първи път отбелязва Деня на глухите. Това става на 23 септември, а после денят прераства в седмица – последната пълна седмица на септември, а някои държави я разширяват до месец, за да могат да се организират повече образователни дейности и дискусии за предизвикателствата пред общността на глухите.
В България вероятно не всеки е чувал за седмица на глухите и може би не всеки се е замислял
как всъщност живеят онези наши съграждани, които общуват чрез жестове.
Въпреки че страната ни прие Закон за жестовия език през 2021 г., все още липсва достатъчно информация за услугите, които държавата предоставя.
Янка Трачук е собственичка на две фирми и председателка на JAMBA – хъб на възможностите. Тя е напълно глуха, но няма да забележите, защото може да чете отлично по устните. Именно това качество я превръща в помощник на хора в нейното положение, които не могат сами да се справят в някои институции. Обикновено им помага с безплатен превод, но тя не е лицензирана преводачка и за услугите ѝ се разбира от уста на уста.
Две жени, на които е помогнала с превод, са Никол Александрова и Десислава Павлова. Никол е току-що завършила студентка от Националната художествена академия. Обикновено се справя сама, но ако има нужда от помощ, би се обърнала към роднините си или колегите в университета. За написването на курсовата си работа е потърсила Янка, която ѝ е помогнала допълнително за усвояване на материала и написване на дипломната работа. По същия начин и Десислава е потърсила помощ за превод в НОИ. И тя като Никол разчита обикновено на роднини за това и винаги си търси преводач.
Според Ашод Дерандонян – изпълнителен директор на фондация „Заслушай се“ и член на Съвета за българския жестов език към МОН, такава е била ситуацията допреди три години. Новият закон признава за самостоятелен жестовия език и се създават условия за по-достъпна среда за граждани със слухови нарушения.
От началото на 2023 г. всички общини в страната са длъжни да осигурят преводачи от жестов език на територията си.
Глухите граждани имат право на 120 часа безвъзмездна преводаческа услуга, а студенти и докторанти разполагат с допълнителни 60 часа на семестър. За осигуряване на услугата се подава заявление до един месец преди началото на следващата календарна година.
По неофициална статистика в България има 120 000 глухи граждани,
а преди приемането на закона 5000 души със слухови нарушения са получавали социална помощ в размер на 80 лв. на година. След въвеждането на услугата за превод обаче са подадени само 140 заявления, пояснява Ашод Дерандонян. По негови думи, проблемът е в липсата на информация относно правата на хората с увреден слух.
Тази информация трябва да бъде предоставена на жестов език от Агенцията за социално подпомагане. Такава информация на жестов език няма. Само е посочена на писмен език и за много глухи хора понякога това е затруднение, защото те не могат в първия момент да осмислят информацията на словесен език,
Съоснователят на агенцията за жестов превод Stray Sheep и експерт по жестов език Борис Бъндев обяснява, че самото подаване на заявление за услугата „безплатен жестов превод“ отказва много хора. Представянето на документите все още става на хартия и пред гише. Методът е остарял, а в днешно време всички очакваме да можем да извършим подобни дейности онлайн – чрез сайт или приложение.
За нещо, което ти е човешко право – това да получиш жестов превод, е измислен възможно най-сложният, най-утежненият начин,
допълва той и посочва като още една причина липсата на обратна връзка за преводачите.
При заявяване на превод в институции със заявителя работи преводачът, който е на разположение в момента. Заявителят няма как да даде оценка за качеството на преводача, нито самите преводачи могат да дадат обратна връзка. Според Бъндев най-добрият вариант е да се обяви конкурс за държавно финансиране на различни агенции, които се занимават с жестов превод. Така се гарантира, че организациите ще се стремят да дават най-доброто от себе си при предоставянето на превод.
Конвенцията за правата на хората с увреждания към ООН, която е подписана и от България, урежда създаването на условия за граждани с увреждания да могат да търсят и получават информация в „достъпен за тях формат“. А в България само някои сайтове имат меню с информация на жестов език. Това са сайтовете на Столичната община, НОИ и НАП, където всеки може да се осведоми за административните услуги. В Общината са назначени трима преводачи от жестов език, а контактният център има и специален мобилен номер във Viber, където глухи граждани могат да подават сигнали за нередности, да получават достъп до обществена информация, да се информират за работното време на администрацията.
Осигуряването на достъп до информация включва и превод в реално време на важни политически изявления. Например липсата на превод по време на речта на британския премиер Киър Стармър по-рано тази година предизвиква негативен отзвук сред глухата общност на Острова. Кралският национален институт за глухи хора (RNID) и Британската асоциация на глухите изтъкват, че осигуряването на преводач е задължение на държавата и глухите граждани трябва да бъдат третирани като равни. Двете организации са на мнение, че липсата на преводач за такова важно събитие е „дълбоко неуважително и недемократично“.
И докато в някои институции достъпът до жестов превод е уреден, в други не е така. Десислава Колева разказва и за
липсата на преводачи в болничните заведения и спешните центрове.
Правото на 120 часа превод включва само посещения при личен лекар.
Когато обаче става дума за болнична подкрепа, болничните заведения са длъжни да осигурят превод от и на жестов език за своя сметка,
категоричен е Ашод Дерандонян. Това се потвърждава и от самия закон за българския жестов език, където е посочено, че финансирането на дейности, свързани с използването и развитието на жестов език, се осъществява със средства от държавния бюджет чрез бюджета на Министерство на труда и социалната политика, бюджета на институциите и за сметка на лечебните заведения.
В чл. 20, ал. 4 от Закона за българския жестов език е записано, че жестов превод извън лимита от 120 часа може да се ползва при „хоспитализиране в лечебни заведения за болнична помощ, центрове за психично здраве, центрове за кожно-венерически заболявания и комплексни онкологични центрове“. Тази услуга все още не е достъпна и при неотложни случаи посред нощ глухите граждани биха срещнали сериозни затруднения при посещение в спешен център, ако изобщо успеят да се обадят на спешна помощ…
Американският закон за хората с увреждания включва специална глава за телекомуникационни услуги за граждани с нарушен слух. За връзка със спешния телефон може да се използва устройство – teletypewriter, което позволява да се изпращат гласови съобщения по телефона. Едната страна пише съобщението като текст, а в другия край на телефона служител в спешната помощ може да чуе съобщението.
Ако обаче нямаш такова устройство, достъпът до спешна помощ е почти невъзможен. Борис Бъндев разказва за случай, в който с него се свързва глух човек с молба да извика линейка за болната му майка. И отново набляга на необходимостта от мобилно приложение за такива ситуации.
Пример за добро осигуряване на жестов превод са болниците под шапката на благотворителната организация „Университетски болници Бирмингам“ в Обединеното кралство, където се предлага жестов превод за всички болнични заведения, но преводачът трябва да бъде заявен поне 48 часа по-рано, за да бъде извършен превод на живо. В противен случай може да се осъществи по телефона или с видеовръзка, като преводът е напълно безплатен във всички случаи и може да бъде заявен онлайн.
Законът за българския жестов език предвижда подкрепа и за родителите на децата със слухови нарушения чрез образователните институции и особено чрез специализираните обслужващи звена (такива, които се занимават с информационна, изследователска, обучителна и други дейности), центровете за подкрепа на личностното развитие, специализираните училища и регионалните центрове, ангажирани с процеса на приобщаващото образование, които следва да „организират и провеждат обучения за родителите на глухи и сляпо-глухи деца по български жестов език за осигуряване на езикова среда на детето“.
Жестовият език е майчин за глухите деца, които се научават да общуват първо чрез движения на ръцете, но с напредването на технологиите и възможността за поставяне на кохлеарни импланти за много родители използването на жестов език се обезсмисля. Въпреки това в Регионалния център за подкрепа на процеса на приобщаващото образование в град Търговище имат специалисти по жестов език, които могат да осигурят обучение за родители при необходимост, твърди директорът Христо Христов.
В академия „Анди и Ая“ се обучават глухи и слабо чуващи деца, но се приемат и чуващи деца на глухи родители. Най-често в академията ходят глухи родители с глухо дете и не е нужно да се провежда обучение по жестов език, но в останалите случаи обученията са добре дошли. Работата с децата може да започне още на едногодишна възраст и да продължи дори до първи курс в университета. Академията позволява да се провеждат занятия онлайн, в които се включват деца от Асеновград, Пловдив, Варна, Свищов, разказва основателката на организацията и специален педагог Даринка Борисова.
Швеция например предлага на родители на глухи деца 240 безплатни часа за обучение по жестов език, като се компенсира и заплатата им, ако не могат да съчетават обучението с работата си. В Швеция се намира и град Йоребру – европейската столица на жестовия език. От близо 160 000 жители население 13 000 използват жестов език, а 2000 са глухи. В града се намира и единствената гимназия за ученици с увреден слух.
В България са останали само три училища за ученици с увреден слух, които разполагат и с пансиони – те са в София, Пловдив и Търговище,
но деца със слухови нарушения могат да се обучават перфектно и в общообразователно училище, като за усвояването на учебния материал им помагат регионалните центрове за подкрепа на процеса на приобщаващо образование и организации като Академия „Анди и Ая“.
Правото на достъп до информация на достъпен за език включва и новините.
Емисиите на БНР могат да се слушат и от глухи хора, но в социалните мрежи. Инициатор на съвместната работа е екипът на Stray Sheep, който е отишъл в радиото с предложение за адаптиране на съдържанието. Мотивите, които Борис Бъндев изтъкна, са, че темпото на говорене в телевизиите е твърде бързо, за да може да се направи качествен превод, а и изживяването като зрител не е твърде приятно.
Глухите хора имат повече нужда водещият да е ясен и визуален, видим за тях, в сравнение с нас, чуващите хора. Набутвайки жестовия преводач в едно малко квадратче, ти ограничаваш и самия него – жестовете му, мимиките му.
пояснява той.
Във видеоемисиите, които се публикуват в социалните мрежи на преводаческата агенция, водещият е в центъра на екрана и жестовият превод е на преден план.
Липсата на преводачески услуги в България вероятно е свързана и с липсата на преводачи от жестов език.
Те все още са малко, като в някои области има само един, а в други няма изобщо. Списък с преводачите от жестов език може да бъде намерен на сайта на Агенцията за хора с увреждания. Там са посочени имената, контакт, населено място и предпочитана сфера на превод, но
броят на преводачите е твърде нисък – едва 35 за цялата страна.
Тъй като не за всяка област има регистриран преводач, Столичната община е подписала 21 споразумения за сътрудничество на областно ниво с 69 общини.
През последните 30 години са били обучени 500 души за жестови преводачи, но само 15 от тях са практикували професията. Според наредба №48 от 2012 г., която впоследствие е отменена, преводачът може да бъде само лице със здрав слух и зрение, а жестовият език се преподава най-добре от естествените си носители, тъй като граматиките на жестов и словесен език се различават. След приемането на новия закон се появяват и първите глухи обучители, като до момента те са под 10, но се очаква броят им да нарасне до 25 в следващите две-три години.
Новият закон осигурява и по-добро заплащане за превод – в момента цената на един час жестов превод е 5% от минималната работна заплата за страната.
Работи се усилено и за създаване на бакалавърска програма по жестов превод в Софийски университет, разказва Ашод Дерандонян.
За нас е много важно глухотата да се представя не като проблем, предизвикателство и т.н., а като един различен културен и езиков свят,
твърди Даринка Борисова от „Анди и Ая“ и добавя:
Не искаме да будим съжаление, напротив даже. И се опитваме да говорим за каузата по много човешки и достъпен начин, така че да бъде разбрана.
A Guide to Quickly Enable and Disable SMT and Hyper-Threading on Ubuntu and Debian
Post Syndicated from Eric Smith original https://www.servethehome.com/a-guide-to-quickly-enable-and-disable-smt-and-hyper-threading-on-ubuntu-and-debian/
This is a quick little guide to enabling and disabling SMT on a Debian or Ubuntu system without having to reboot the system
The post A Guide to Quickly Enable and Disable SMT and Hyper-Threading on Ubuntu and Debian appeared first on ServeTheHome.
S11 E23: Disability Benefits, Trump, Vance & Haiti: 9/22/24: Last Week Tonight with John Oliver
Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=_hIOdiYYSnc
The World’s First Space-Age Vehicle
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=jN2sycTHayw
Bringing Grab’s Live Activity to Android: Enhancing user experience through custom notifications
Post Syndicated from Grab Tech original https://engineering.grab.com/live-activity-2
In May 2023, Grab unveiled the Live Activity feature for iOS, which received positive feedback from users. Live Activity is a feature that enhances user experience by displaying a user interface (UI) outside of the app, delivering real-time updates and interactive content. At Grab, we leverage this feature to keep users informed about their order updates without requiring them to manually open the app.
While Live Activity is a native iOS feature provided by Apple, there is currently no official Android equivalent. However, we are determined to bring this immersive experience to Android users. Inspired by the success of Live Activity on iOS, we have embarked on design explorations and feasibility studies to ensure the seamless integration of Live Activity into the Android platform. Our ultimate goal is to provide Android users with the same level of convenience and real-time updates, elevating their Grab experience.
Product Exploration
In July 2023, we took a proactive step by forming a dedicated working group with the specific goal of exploring Live Activity on the Android platform. Our mindset was focused on quickly enabling the MVP (Minimum Viable Product) of this feature for Android users. We focused on enabling Grab users to track food and mart orders on Live Activity as our first use-case. We also designed the Live Activity module as an extendable platform, allowing easy adoption by other Grab internal verticals such as the Express and Transport teams.
The team kicked off by analysing the current solution and end-to-end flow of Live Activity on iOS. The objective was to uncover opportunities on how we could leverage the existing platform approach.

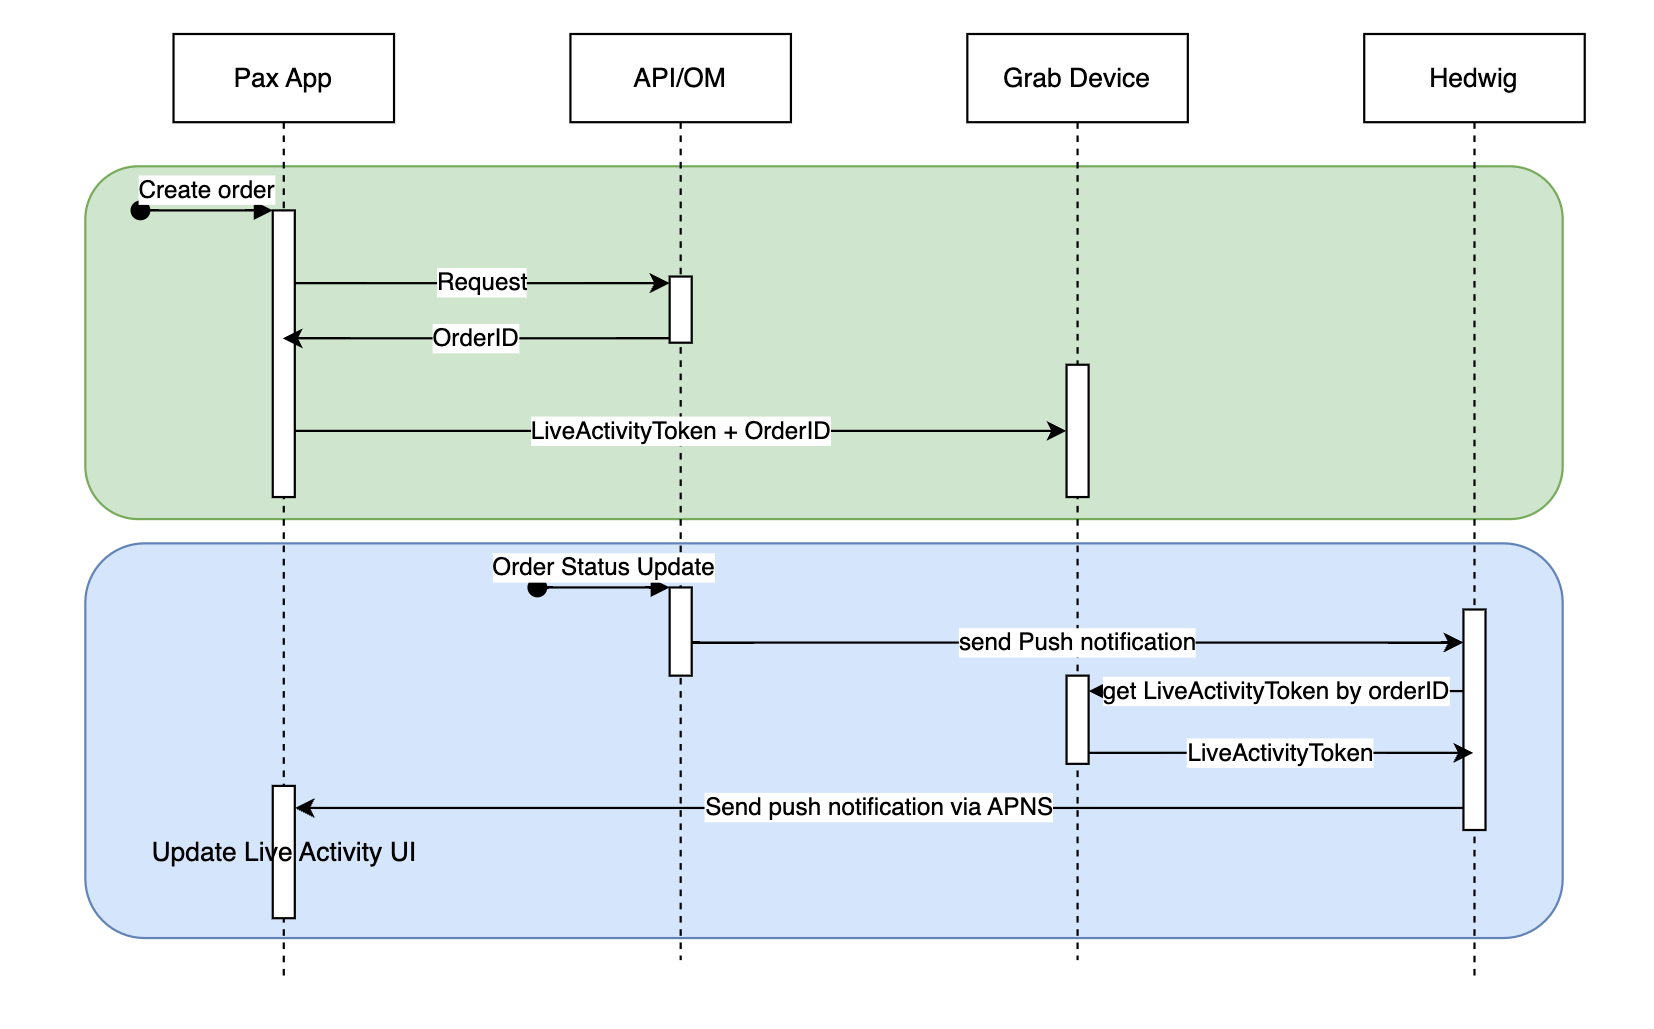
The first thing that caught our attention was that there is no Live Activity Token (also known as Push Token) concept on Android. Push Token is a token generated from the ActivityKit framework and used to remotely start, update, and end Live Activity notifications on iOS.
Our goal was to match the Live Activity set-up of iOS in Android, which was a challenge due to the missing Push Token. This required us to think outside the box and develop an innovative workaround. After multiple brainstorming sessions, the team developed two potential solutions, Solution 1 and Solution 2, as illustrated below:
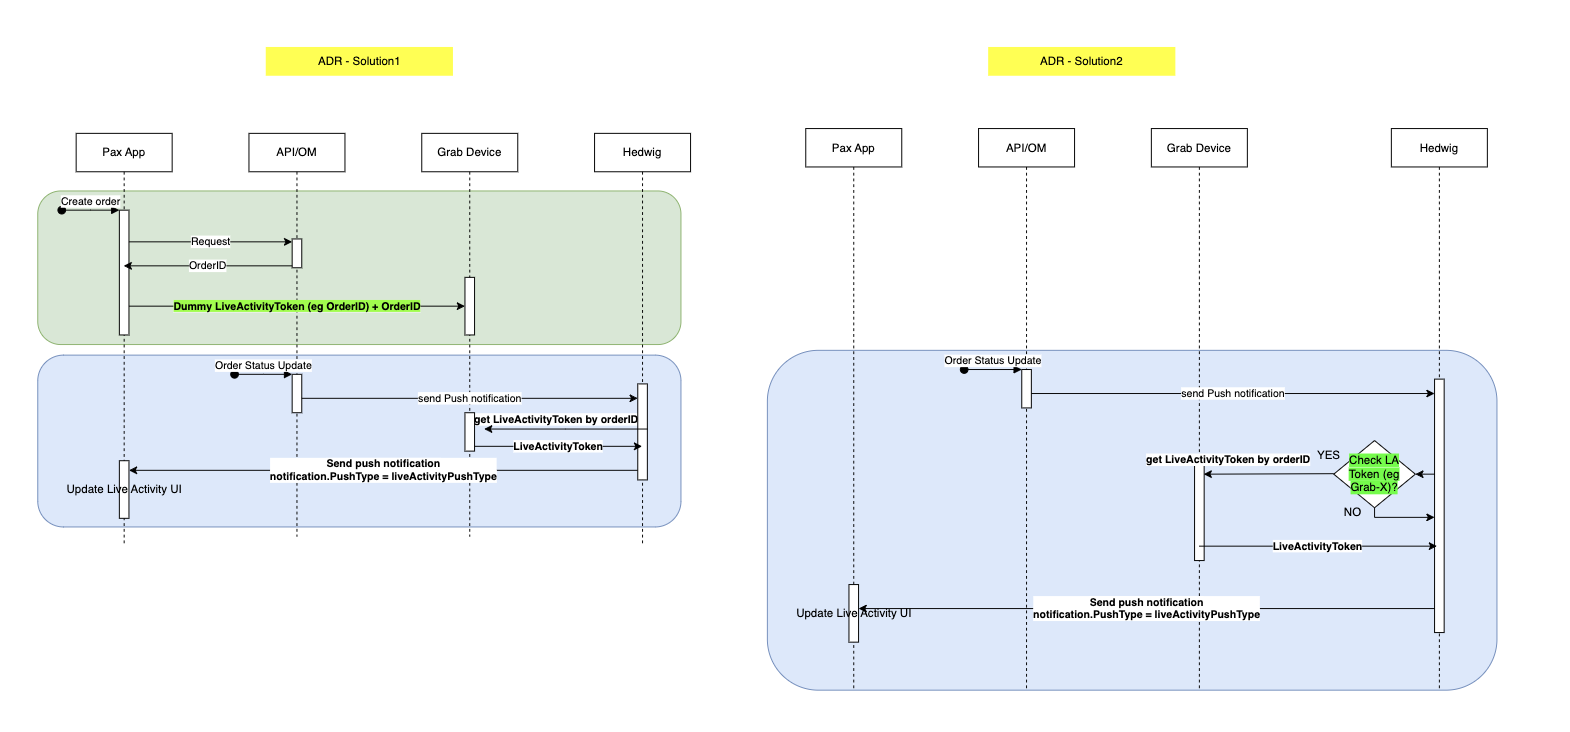
We evaluated the two solutions. The first solution is to substitute the Push Token with a placeholder value, serving as a distinctive notification identifier. Whereas, the second solution involves the Hedwig service, our in-house message delivery service. We proposed to bypass the Live Activity token check process specifically for Android devices. Following extensive discussions, we decided to proceed with the first solution, which ensures consistency in the technical approach between Android and iOS platforms. Additionally, this solution allows us to ensure that notifications are only pushed to the devices that support the Live Activity feature. This decision strikes a good balance between efficiency and compatibility.
UI Components
Starting with a kick-off project meeting where we showcased our plans and proposed solutions to our stakeholders, the engineering team presented two native Android UI components that could be utilised to replicate Live Activity: the Notification View and the Floating View.
The Notification View is a component located in the notification drawer (and potentially on the Lock Screen) that fulfils the most basic use-case of the Live Activity feature. It enables Android users to access information without the need to open the app. Since the standard notification template only allows developers to display a single content title, a content subtitle, and one image, it falls short of meeting our Live Activity UI requirements. To overcome this limitation, custom notifications with custom layouts are needed.
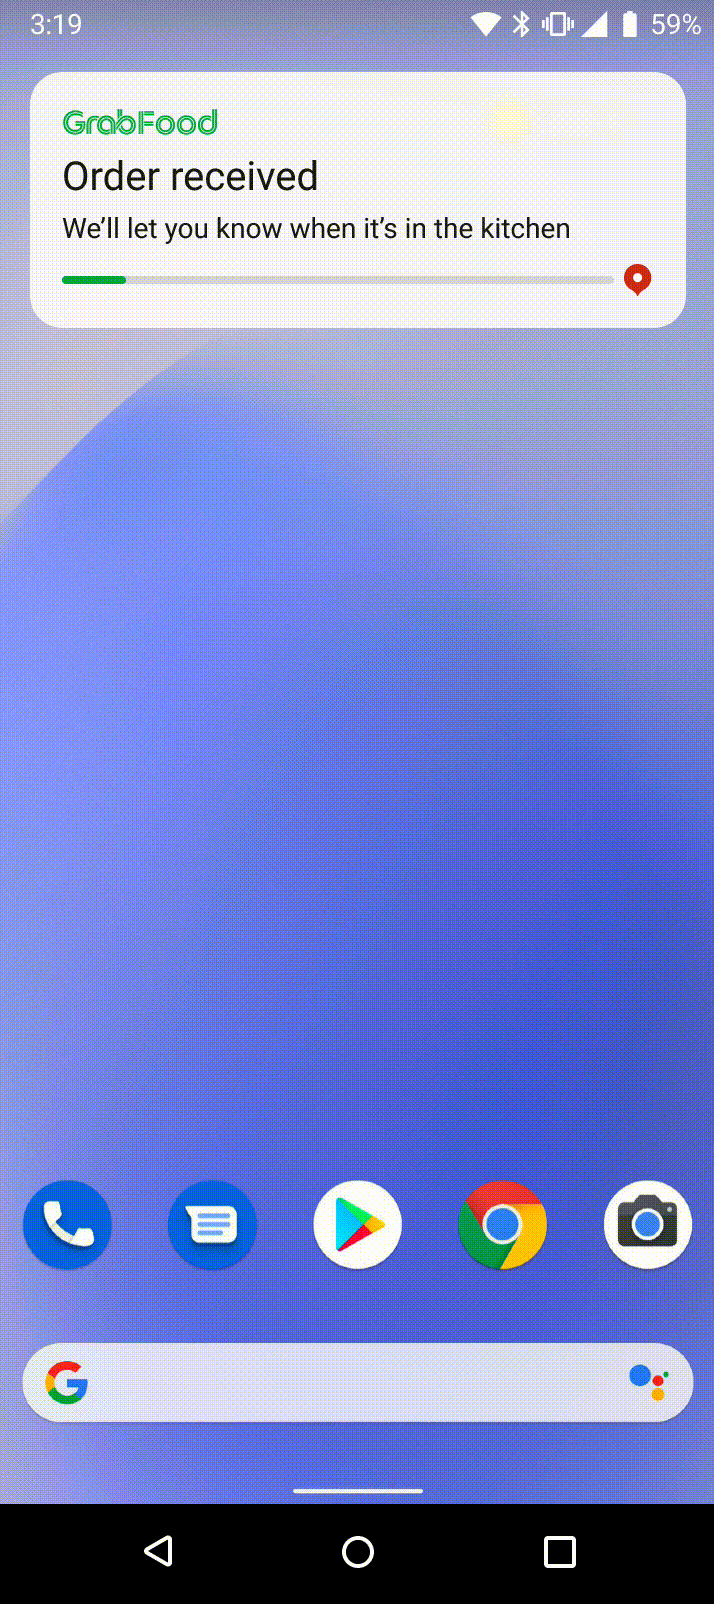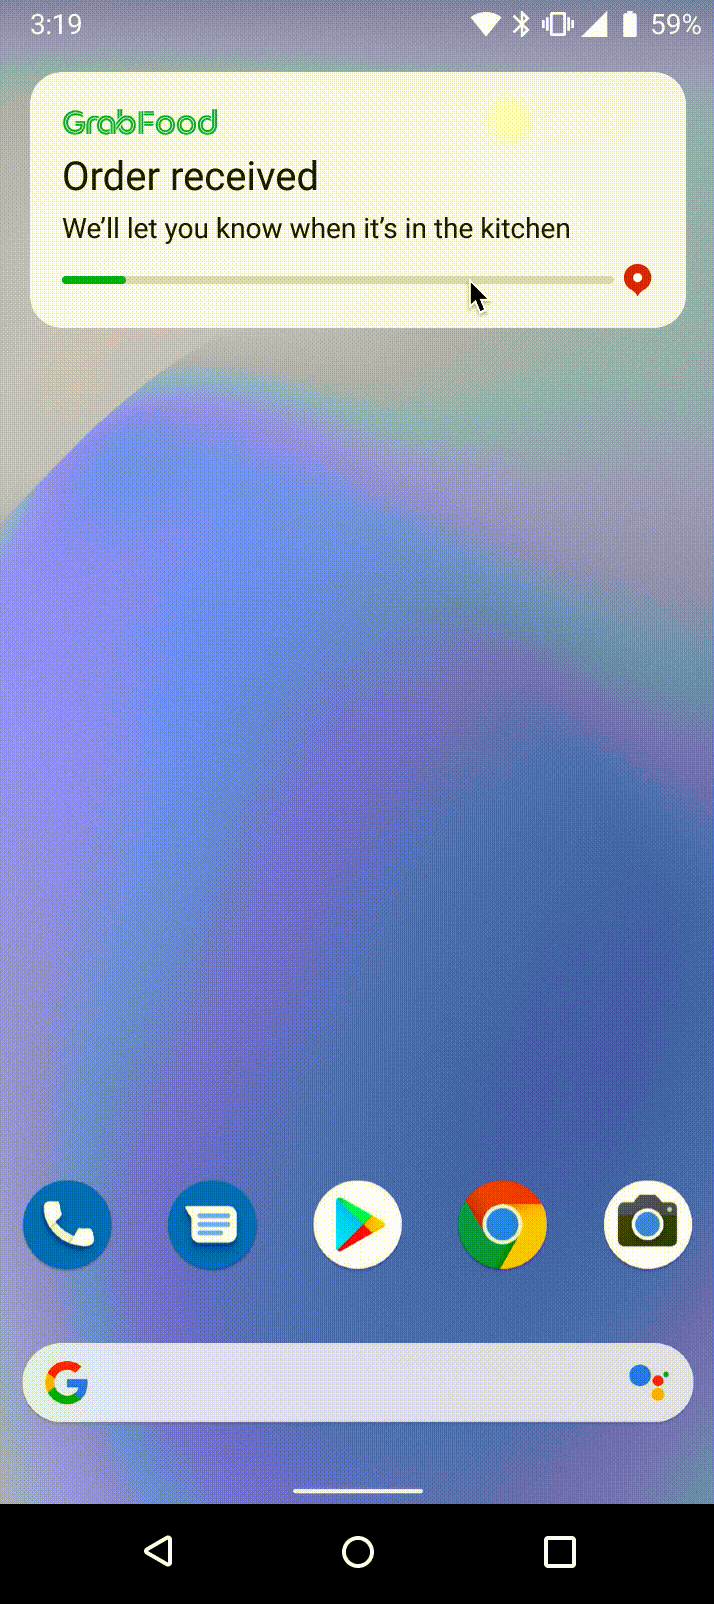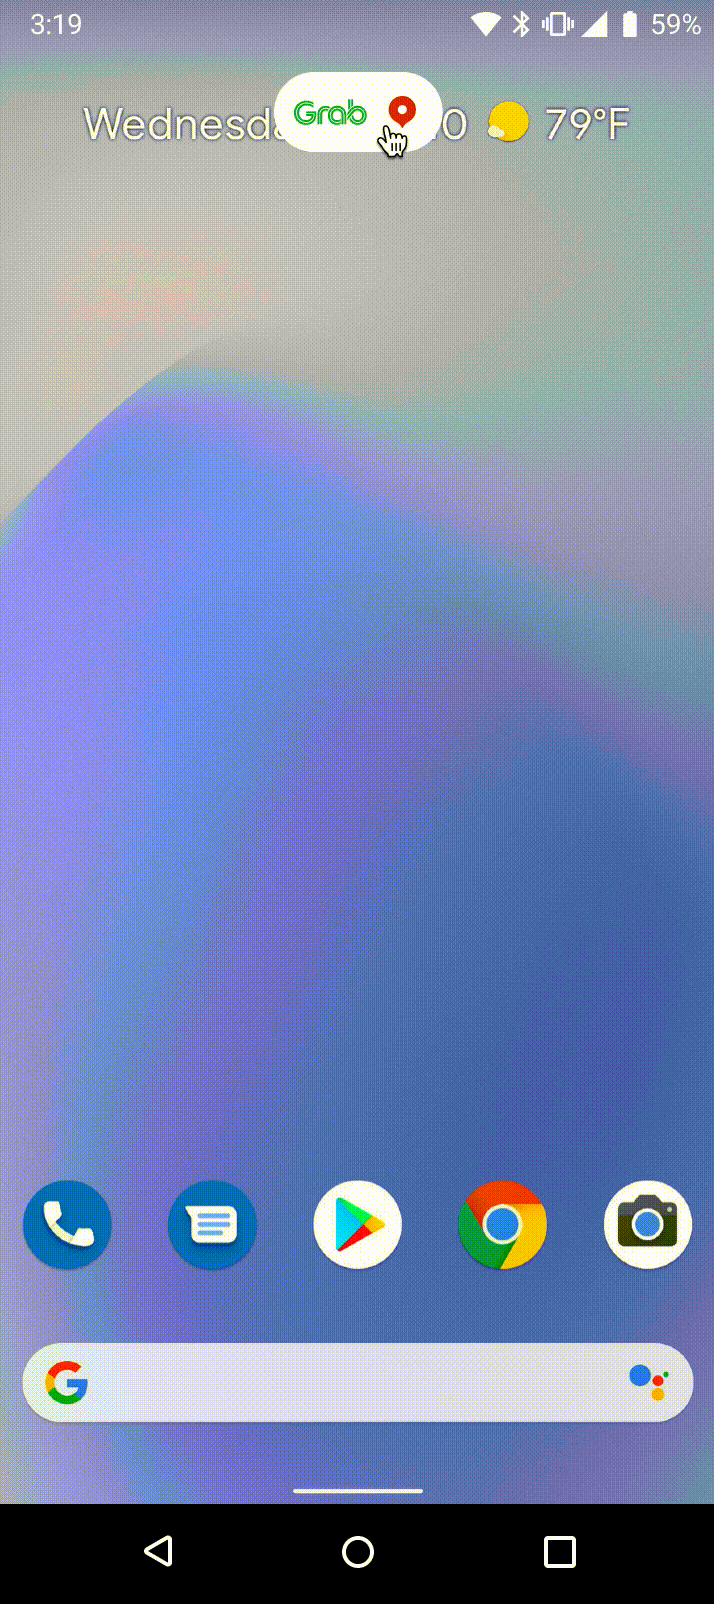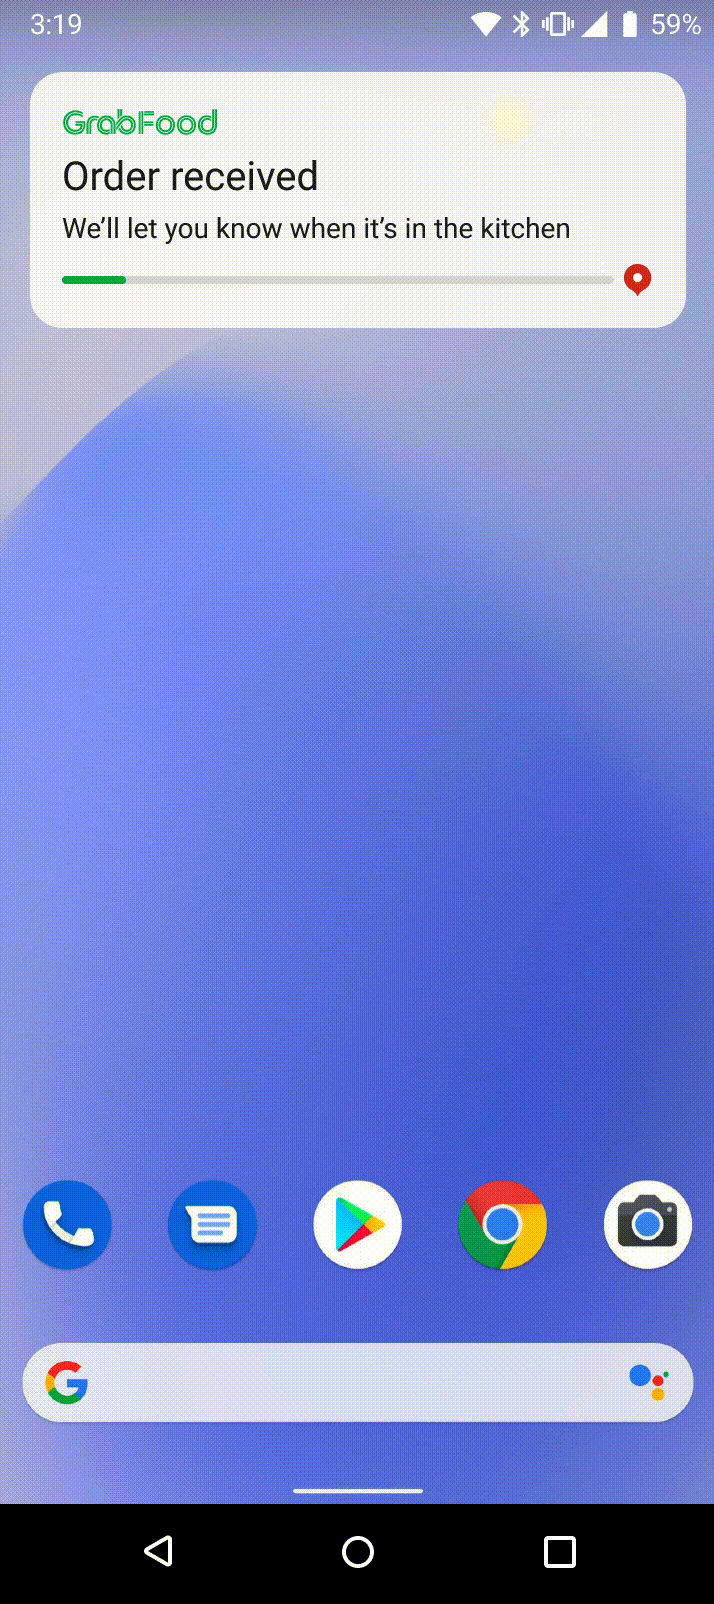
One of the key advantages of custom notifications is that they do not require any additional new permissions, ensuring a smooth user experience. Additionally, Android users are accustomed to checking their notifications from the notification tray, making it a familiar and intuitive interaction. However, it is important to acknowledge that custom notifications rely on a remote view, which can pose restrictions on rendering only specific views. On top of that, custom notifications provide a limited space for content – limited to 48dp when collapsed and 252dp when expanded.
The Floating View is a component that will appear above all the applications in Android. It adds the convenience of accessing the information when the device is unlocked or when the user is on another app.
The use of a Floating View offers greater flexibility to the view by eliminating the reliance on a remote view. However, it’s important to be aware of the potential limitations associated with this approach. These limitations include the requirement for screen space, which can potentially impact other app functionalities and cause frustration for users. Additionally, if we intend to display multiple order updates, we may require even more space, taking into account that Grab allows users to place multiple orders. Furthermore, the Floating View feature requires an extra “Draw over other apps” permission, a setting that allows an app to display information on top of other apps on your screen.
After thoughtful deliberation, we concluded that custom notifications provide a more consistent and user-friendly solution for implementing Grab’s Live Activity feature on Android. They offer compatibility, non-intrusiveness, no extra permissions, and the flexibility of silent notifications, ensuring an optimised user experience.
Building Grab Android’s “Live Activity”
We began developing the Live Activity feature by focusing on Food and Mart for the MVP. However, we prioritised potential future use cases for other verticals by examining the existing functionality of the Grab iOS Live Activity feature. By considering these factors from the start, we need to make sure that we build an extendable and flexible solution that caters to different verticals and their various use-cases.
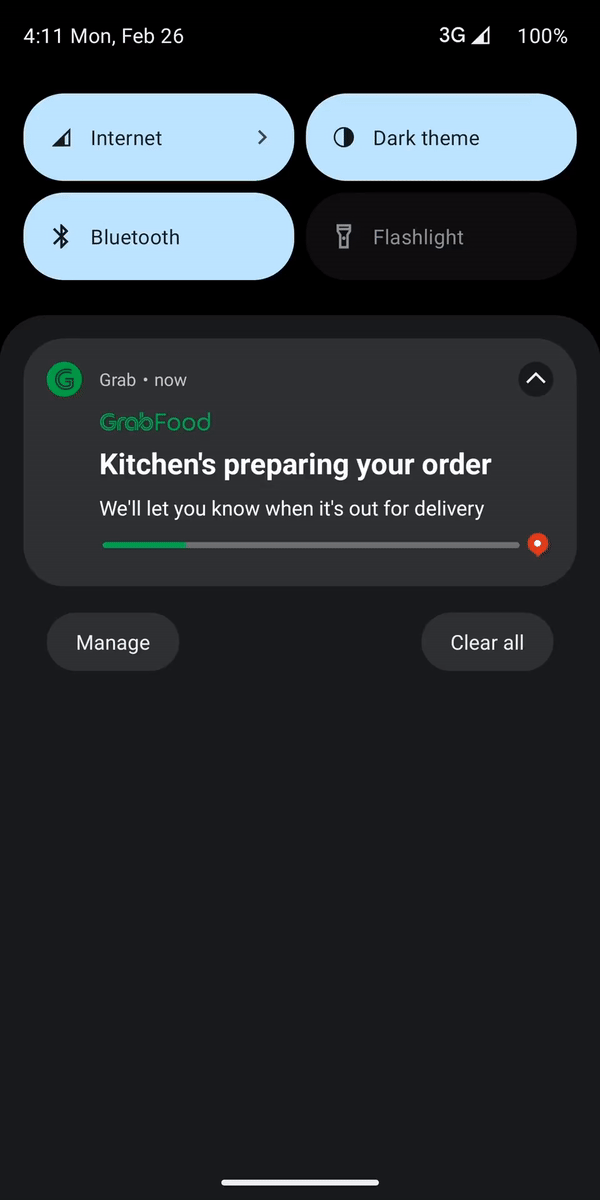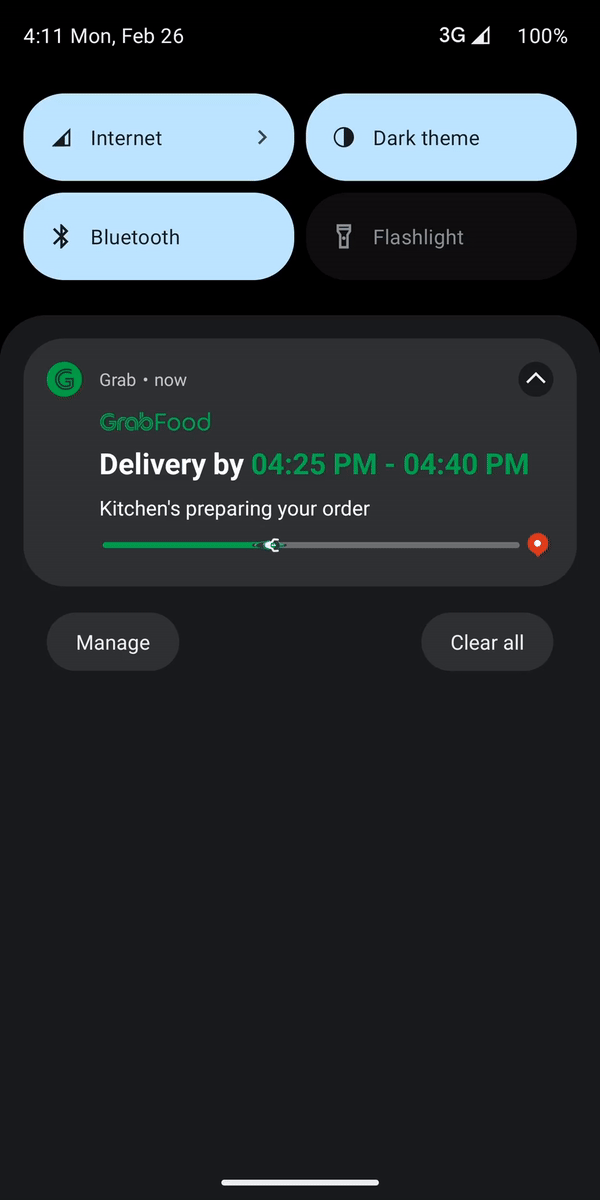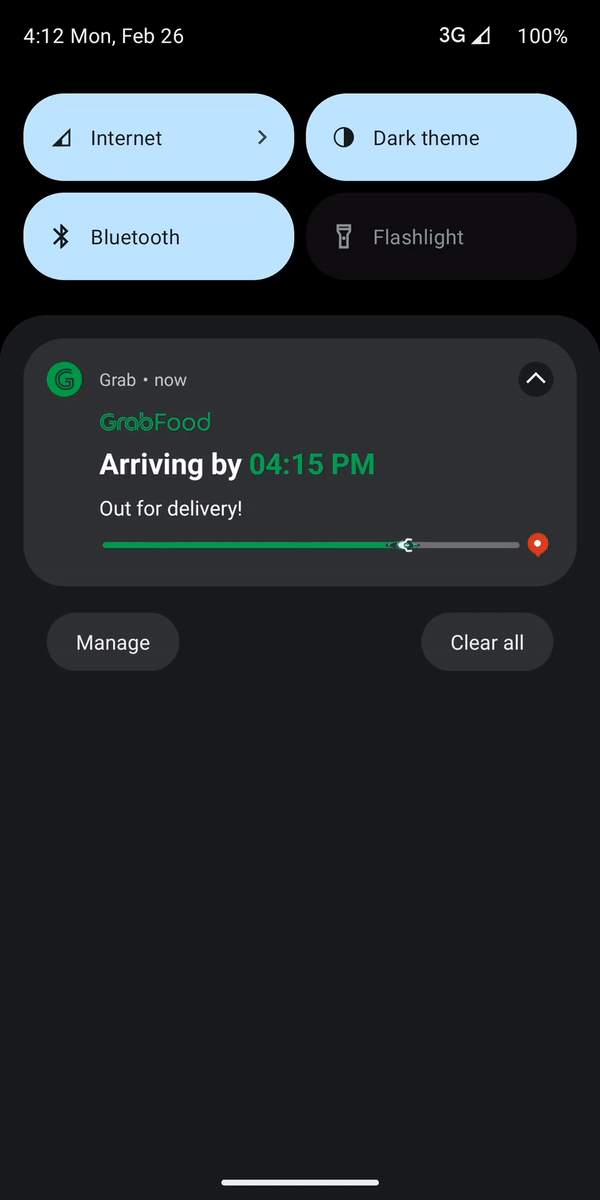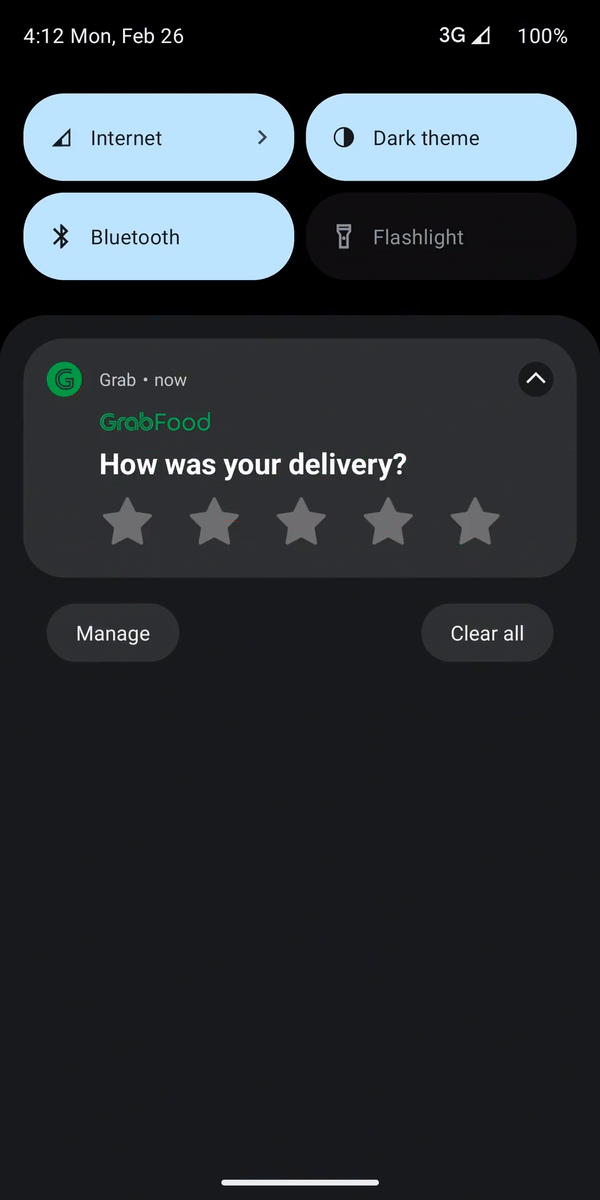
As we set out to design Grab’s Android Live Activity module, we broke down the task into three key components:
- Registering Live Activity Token
In order to enable Hedwig services to send Live Activity notifications to devices, it is necessary to register a Live Activity Token for a specific order to Grab Devices services (refer to figure 1 for the iOS flow). As this use-case is applicable across various verticals in iOS, we have designed a LiveActivityIntegrationManager class specifically to handle this functionality.
interface LiveActivityIntegrationManager {
    /\*\*
     \* To start live activity journey
     \* @param vertical refers to vertical name
     \* @param id refers to unique id which is used to differentiate live activity UI instances
     \* eg: Food will use orderID as id, transport can pass rideID
     \*\*/
    fun startLiveActivity(vertical: Vertical, id: String): Completable

    fun updateLiveActivity(id: String, attributes: LiveActivityAttributes)

    fun cancelLiveActivity(id: String)
}
Our goal is to provide developers with an easy implementation of Live Activity in the Grab app. Developers can simply utilize the startLiveActivity() function to register the token to Grab Devices by passing the vertical name and unique ID as parameters.
- Notification Listener and Payload Mapping
To handle Live Activity notifications in Android, it is necessary to listen to the Live Activity notification payload and map it to LiveActivityAttributes. Taking into consideration the initial Live Activity design (refer to figure 3), we need to analyse the variables necessary for this process. As a result, we break down the Live Activity UI into different UI elements and layouts, as follows:
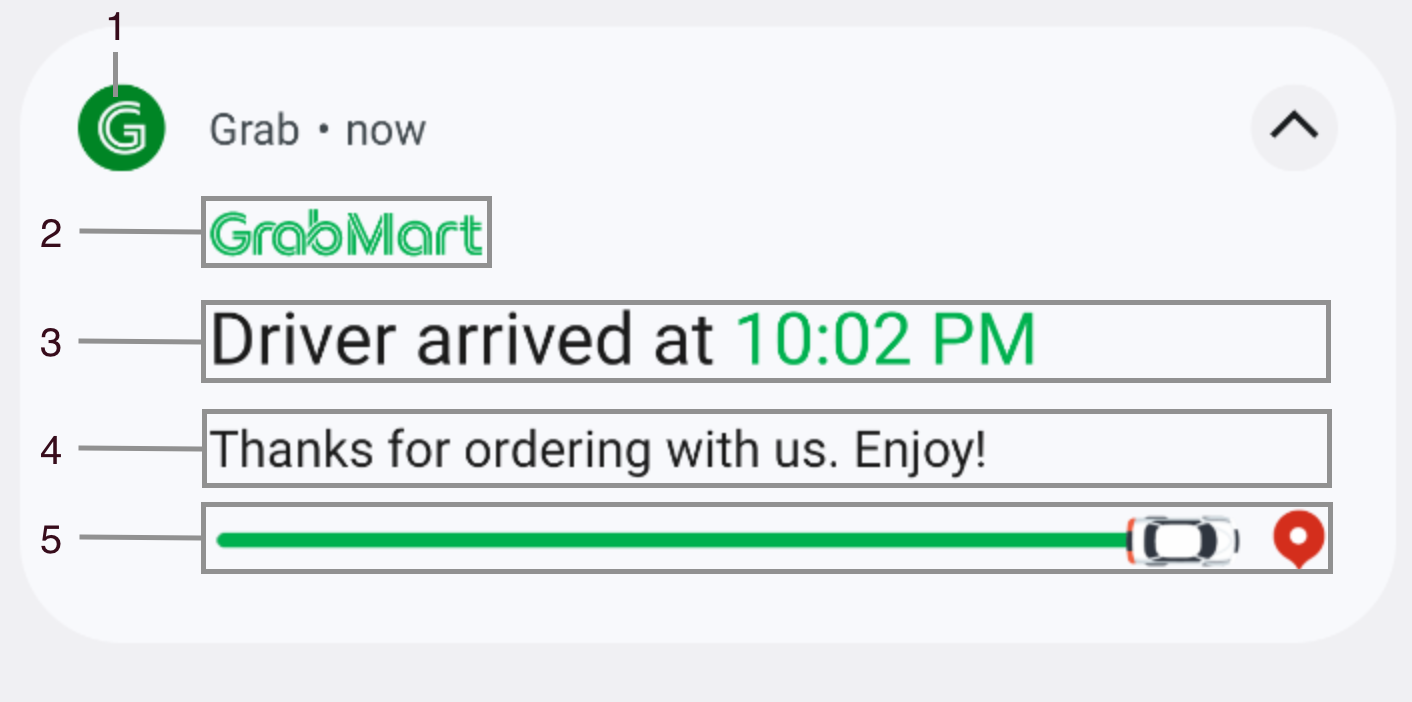
- App Icon – labeled as 1 in Figure 6.
This view always shows the Grab app icon. - Header Icon – labeled as 2 in Figure 6.
This view is an image view that could be set with icon resources. - Content Title View – labeled as 3 in Figure 6.
This view is a placeholder that could be set with a text or custom remote view. - Content Text View – labeled as 4 in Figure 6.
This view is a placeholder that could be set with a text or custom remote view. - Footer View – labeled as 5 in Figure 6.
This view is a placeholder that could be set with icon resources, bitmap, or custom remote view.
Decomposing the UI into different parts allows us to clearly understand of the UI components that need to maintain consistency across different use-cases, as well as the elements that can be easily customised and configured based on specific requirements. As a result, we have designed the LiveActivityAttributes class that serves as a container that encompasses all the necessary configurations required for rendering the Live Activity.
class LiveActivityAttributes private constructor(
    val iconRes: Int?,
    val headerIconRes: Int?,
    val contentTitle: CharSequence?,
    val contentTitleStyle: ContentStyle.TitleStyle?,
    val customContentTitleView: LiveActivityCustomView?,
    val contentText: CharSequence?,
    val contentTextStyle: ContentStyle.TextStyle?,
    val customContentTextView: LiveActivityCustomView?,
    val footerIconRes: Int?,
    val footerBitmap: Bitmap?,
    val footerProgressBarProgress: Float?,
    val footerProgressBarStyle: ProgressBarStyle?,
    val footerRatingBarAttributes: RatingBarAttributes?,
    val customFooterView: LiveActivityCustomView?,
    val contentIntent: PendingIntent?,
    …
)
- Payload Rendering
To ensure a clear separation of responsibilities, we have designed a separate class called LiveActivityManager. This dedicated class is responsible for the mapping of LiveActivityAttributes to Notifications. The generated notifications are then utilised by Android’s NotificationManager class to be posted and displayed accordingly.
interface LiveActivityManager {
    /\*\*
     \* Post a Live Activity to be shown in the status bar, stream, etc.
     \*
     \* @param id           the ID of the Live Activity
     \* @param attributes the LiveActivity to post to the system
     \*/
    fun notify(id: Int, attributes: LiveActivityAttributes)

    fun cancel(id: Int)
}
What’s Next?
We are delighted to announce that we have successfully implemented Grab’s Android version of the Live Activity feature for Express and Transport products. Furthermore, we plan to extend this feature to the Driver and Merchant applications as well. We understand the value this feature brings to our users and are committed to enhancing it further. Stay tuned for upcoming updates and enhancements to the Live Activity feature as we continue to improve and expand its capabilities across various verticals.
Join us
Grab is the leading superapp platform in Southeast Asia, providing everyday services that matter to consumers. More than just a ride-hailing and food delivery app, Grab offers a wide range of on-demand services in the region, including mobility, food, package and grocery delivery services, mobile payments, and financial services across 428 cities in eight countries.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
Physics Lab Thermostat
Post Syndicated from xkcd.com original https://xkcd.com/2989/