While wandering the Computex 2026 showfloor, we visited MiTAC’s booth. The prolific server vendor had numerous products on display, including racks of GPU systems, storage, and even diamond cooled servers
Outlining their hardware plans for the modern data center, Dell has announced their EPYC and Xeon-based 18th generation PowerEdge servers, as well as a next-gen storage server, the PowerStore Elite
Ahead of June pre-orders, AMD is releasing more information about their forthcoming AI dev box, the Ryzen AI Halo. The AI mini-PC will come pre-loaded with a comprehensive AMD software stack and carry a $3999 price tag
AMD is adding a trio of new chips to its Ryzen AI Max portfolio. The 400 series chips will bring support for up to 192GB of memory to AI systems, allowing for larger local models than ever before
Looking at the role of compilers in SPEC CPU 2026 performance, we have tested the benchmark suite on LLVM 22. The newest compiler provides a meaningful improvement to benchmark scores for multiple architectures
AMD has released a PCIe version of its flagship MI350 accelerators, the MI350P. Half of a MI350X, the card is aimed at customers who need to fit an modern AI accelerator into a traditional PCIe server
After nearly a decade, SPEC has released a new version of its industry-defining CPU benchmark, SPEC CPU 2026. We take a look at what’s new, as well as the new benchmark’s performance on a modern AMD, Intel, and NVIDIA CPU trio
AMD’s Ryzen 9000 series desktop processors are by now well into the second half of their lifecycle as AMD’s leading-edge desktop chips. With a complete product stack in play – ranging from 6 up to 16 CPU cores on a single chip – In most generations this would be where AMD would stand pat on […]
The Arctic Freezer 4U-SP5 is something really interesting. As the name suggests, it is a 4U cooler that is designed to cool AMD SP5 platform processors. For those who are buying AMD EPYC 9004/9005 series processors like Genoa, Bergamo, and Turin. Perhaps the best part is that these sell for around $55, which is less […]
Two years ago, Cloudflare deployed our 12th Generation server fleet, based on AMD EPYC™ Genoa-X processors with their massive 3D V-Cache. That cache-heavy architecture was a perfect match for our request handling layer, FL1 at the time. But as we evaluated next-generation hardware, we faced a dilemma — the CPUs offering the biggest throughput gains came with a significant cache reduction. Our legacy software stack wasn’t optimized for this, and the potential throughput benefits were being capped by increasing latency.
This blog describes how the FL2 transition, our Rust-based rewrite of Cloudflare’s core request handling layer, allowed us to prove Gen 13’s full potential and unlock performance gains that would have been impossible on our previous stack. FL2 removes the dependency on the larger cache, allowing for performance to scale with cores while maintaining our SLAs. Today, we are proud to announce the launch of Cloudflare’s Gen 13 based on AMD EPYC™ 5th Gen Turin-based servers running FL2, effectively capturing and scaling performance at the edge.
What AMD EPYCTurin brings to the table
AMD’s EPYC™ 5th Generation Turin-based processors deliver more than just a core count increase. The architecture delivers improvements across multiple dimensions of what Cloudflare servers require.
2x core count: up to 192 cores versus Gen 12’s 96 cores, with SMT providing 384 threads
Improved IPC: Zen 5’s architectural improvements deliver better instructions-per-cycle compared to Zen 4
Better power efficiency: Despite the higher core count, Turin consumes up to 32% fewer watts per core compared to Genoa-X
DDR5-6400 support: Higher memory bandwidth to feed all those cores
However, Turin’s high density OPNs make a deliberate tradeoff: prioritizing throughput over per core cache. Our analysis across the Turin stack highlighted this shift. For example, comparing the highest density Turin OPN to our Gen 12 Genoa-X processors reveals that Turin’s 192 cores share 384MB of L3 cache. This leaves each core with access to just 2MB, one-sixth of Gen 12’s allocation. For any workload that relies heavily on cache locality, which ours did, this reduction posed a serious challenge.
Generation
Processor
Cores/Threads
L3 Cache/Core
Gen 12
AMD Genoa-X 9684X
96C/192T
12MB (3D V-Cache)
Gen 13 Option 1
AMD Turin 9755
128C/256T
4MB
Gen 13 Option 2
AMD Turin 9845
160C/320T
2MB
Gen 13 Option 3
AMD Turin 9965
192C/384T
2MB
Diagnosing the problem with performance counters
For our FL1 request handling layer, NGINX- and LuaJIT-based code, this cache reduction presented a significant challenge. But we didn’t just assume it would be a problem; we measured it.
During the CPU evaluation phase for Gen 13, we collected CPU performance counters and profiling data to identify exactly what was happening under the hood using AMD uProf tool. The data showed:
L3 cache miss rates increased dramatically compared to Gen 12’s server equipped with 3D V-cache processors
Memory fetch latency dominated request processing time as data that previously stayed in L3 now required trips to DRAM
The latency penalty scaled with utilization as we pushed CPU usage higher, and cache contention worsened
L3 cache hits complete in roughly 50 cycles; L3 cache misses requiring DRAM access take 350+ cycles, an order of magnitude difference. With 6x less cache per core, FL1 on Gen 13 was hitting memory far more often, incurring latency penalties.
The tradeoff: latency vs. throughput
Our initial tests running FL1 on Gen 13 confirmed what the performance counters had already suggested. While the Turin processor could achieve higher throughput, it came at a steep latency cost.
Metric
Gen 12 (FL1)
Gen 13 – AMD Turin 9755 (FL1)
Gen 13 – AMD Turin 9845 (FL1)
Gen 13 – AMD Turin 9965 (FL1)
Delta
Core count
baseline
+33%
+67%
+100%
FL throughput
baseline
+10%
+31%
+62%
Improvement
Latency at low to moderate CPU utilization
baseline
+10%
+30%
+30%
Regression
Latency at high CPU utilization
baseline
> 20%
> 50%
> 50%
Unacceptable
The Gen 13 evaluation server with AMD Turin 9965 that generated 60% throughput gain was compelling, and the performance uplift provided the most improvement to Cloudflare’s total cost of ownership (TCO).
But a more than 50% latency penalty is not acceptable. The increase in request processing latency would directly impact customer experience. We faced a familiar infrastructure question: do we accept a solution with no TCO benefit, accept the increased latency tradeoff, or find a way to boost efficiency without adding latency?
Incremental gains with performance tuning
To find a path to an optimal outcome, we collaborated with AMD to analyze the Turin 9965 data and run targeted optimization experiments. We systematically tested multiple configurations:
Hardware Tuning: Adjusting hardware prefetchers and Data Fabric (DF) Probe Filters, which showed only marginal gains
Scaling Workers: Launching more FL1 workers, which improved throughput but cannibalized resources from other production services
CPU Pinning & Isolation: Adjusting workload isolation configurations to find optimal mix, with limited success
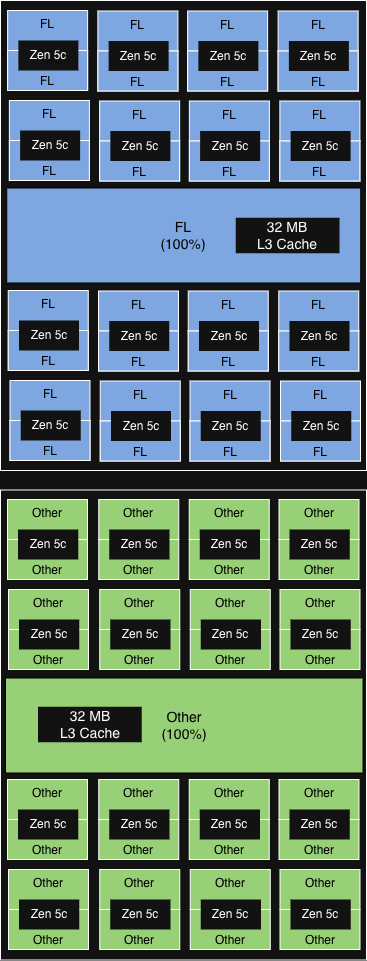
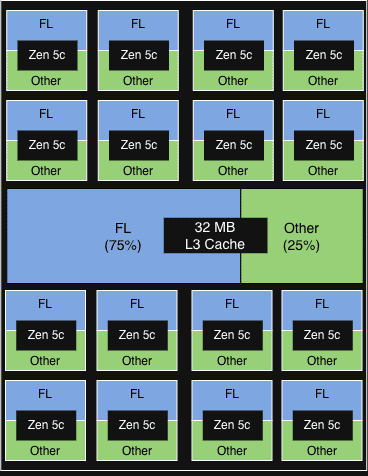
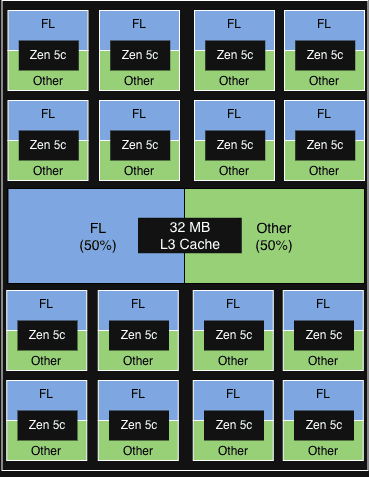
The configuration that ultimately provided the most value was AMD’s Platform Quality of Service (PQOS). PQOS extensions enable fine-grained regulation of shared resources like cache and memory bandwidth. Since Turin processors consist of one I/O Die and up to 12 Core Complex Dies (CCDs), each sharing an L3 cache across up to 16 cores, we put this to the test. Here is how the different experimental configurations performed.
First, we used PQOS to allocate a dedicated L3 cache share within a single CCD for FL1, the gains were minimal. However, when we scaled the concept to the socket level, dedicating an entire CCD strictly to FL1, we saw meaningful throughput gains while keeping latency acceptable.
Configuration
Description
Illustration
Performance gain
NUMA-aware core affinity (equivalent to PQOS at socket level)
6 out of 12 CCD (aligned with NUMA domain) run FL.
32MB L3 cache in each CCD shared among all cores.
>15% incremental
throughput gain
PQOS config 1
1 of 2 vCPU on each physical core in each CCD runs FL.
FL gets 75% of the 32MB L3 cache of each CCD.
< 5% incremental throughput gain
Other services show minor signs of degradation
PQOS config 2
1 of 2 vCPU in each physical core in each CCD runs FL.
FL gets 50% of the 32MB L3 cache of each CCD.
< 5% incremental throughput gain
PQOS config 3
2 vCPU on 50% of the physical core in each CCD runs FL.
FL gets 50% of the 32MB L3 cache of each CCD.
< 5% incremental throughput gain
The opportunity: FL2 was already in progress
Hardware tuning and resource configuration provided modest gains, but to truly unlock the performance potential of the Gen 13 architecture, we knew we would have to rewrite our software stack to fundamentally change how it utilized system resources.
Fortunately, we weren’t starting from scratch. As we announced during Birthday Week 2025, we had already been rebuilding FL1 from the ground up. FL2 is a complete rewrite of our request handling layer in Rust, built on our Pingora and Oxy frameworks, replacing 15 years of NGINX and LuaJIT code.
The FL2 project wasn’t initiated to solve the Gen 13 cache problem — it was driven by the need for better security (Rust’s memory safety), faster development velocity (strict module system), and improved performance across the board (less CPU, less memory, modular execution).
FL2’s cleaner architecture, with better memory access patterns and less dynamic allocation, might not depend on massive L3 caches the way FL1 did. This gave us an opportunity to use the FL2 transition to prove whether Gen 13’s throughput gains could be realized without the latency penalty.
Proving it out: FL2 on Gen 13
As the FL2 rollout progressed, production metrics from our Gen 13 servers validated what we had hypothesized.
Metric
Gen 13 AMD Turin 9965 (FL1)
Gen 13 AMD Turin 9965 (FL2)
FL requests per CPU%
baseline
50% higher
Latency vs Gen 12
baseline
70% lower
Throughput vs Gen 12
62% higher
100% higher
The out-of-the-box efficiency gains on our new FL2 stack were substantial, even before any system optimizations. FL2 slashed the latency penalty by 70%, allowing us to push Gen 13 to higher CPU utilization while strictly meeting our latency SLAs. Under FL1, this would have been impossible.
By effectively eliminating the cache bottleneck, FL2 enables our throughput to scale linearly with core count. The impact is undeniable on the high-density AMD Turin 9965: we achieved a 2x performance gain, unlocking the true potential of the hardware. With further system tuning, we expect to squeeze even more power out of our Gen 13 fleet.
Generational improvement with Gen 13
With FL2 unlocking the immense throughput of the high-core-count AMD Turin 9965, we have officially selected these processors for our Gen 13 deployment. Hardware qualification is complete, and Gen 13 servers are now shipping at scale to support our global rollout.
Performance improvements
Gen 12
Gen 13
Processor
AMD EPYC™ 4th Gen Genoa-X 9684X
AMD EPYC™ 5th Gen Turin 9965
Core count
96C/192T
192C/384T
FL throughput
baseline
Up to +100%
Performance per watt
baseline
Up to +50%
Gen 13 business impact
Up to 2x throughput vs Gen 12 for uncompromising customer experience: By doubling our throughput capacity while staying within our latency SLAs, we guarantee our applications remain fast and responsive, and able to absorb massive traffic spikes.
50% better performance/watt vs Gen 12 for sustainable scaling: This gain in power efficiency not only reduces data center expansion costs, but allows us to process growing traffic with a vastly lower carbon footprint per request.
60% higher rack throughput vs Gen 12 for global edge upgrades: Because we achieved this throughput density while keeping the rack power budget constant, we can seamlessly deploy this next generation compute anywhere in the world across our global edge network, delivering top tier performance exactly where our customers want it.
Gen 13 + FL2: ready for the edge
Our legacy request serving layer FL1 hit a cache contention wall on Gen 13, forcing an unacceptable tradeoff between throughput and latency. Instead of compromising, we built FL2.
Designed with a vastly leaner memory access pattern, FL2 removes our dependency on massive L3 caches and allows linear scaling with core count. Running on the Gen 13 AMD Turin platform, FL2 unlocks 2x the throughput and a 50% boost in power efficiency all while keeping latency within our SLAs. This leap forward is a great reminder of the importance of hardware-software co-design. Unconstrained by cache limits, Gen 13 servers are now ready to be deployed to serve millions of requests across Cloudflare’s global network.
If you’re excited about working on infrastructure at global scale, we’re hiring.
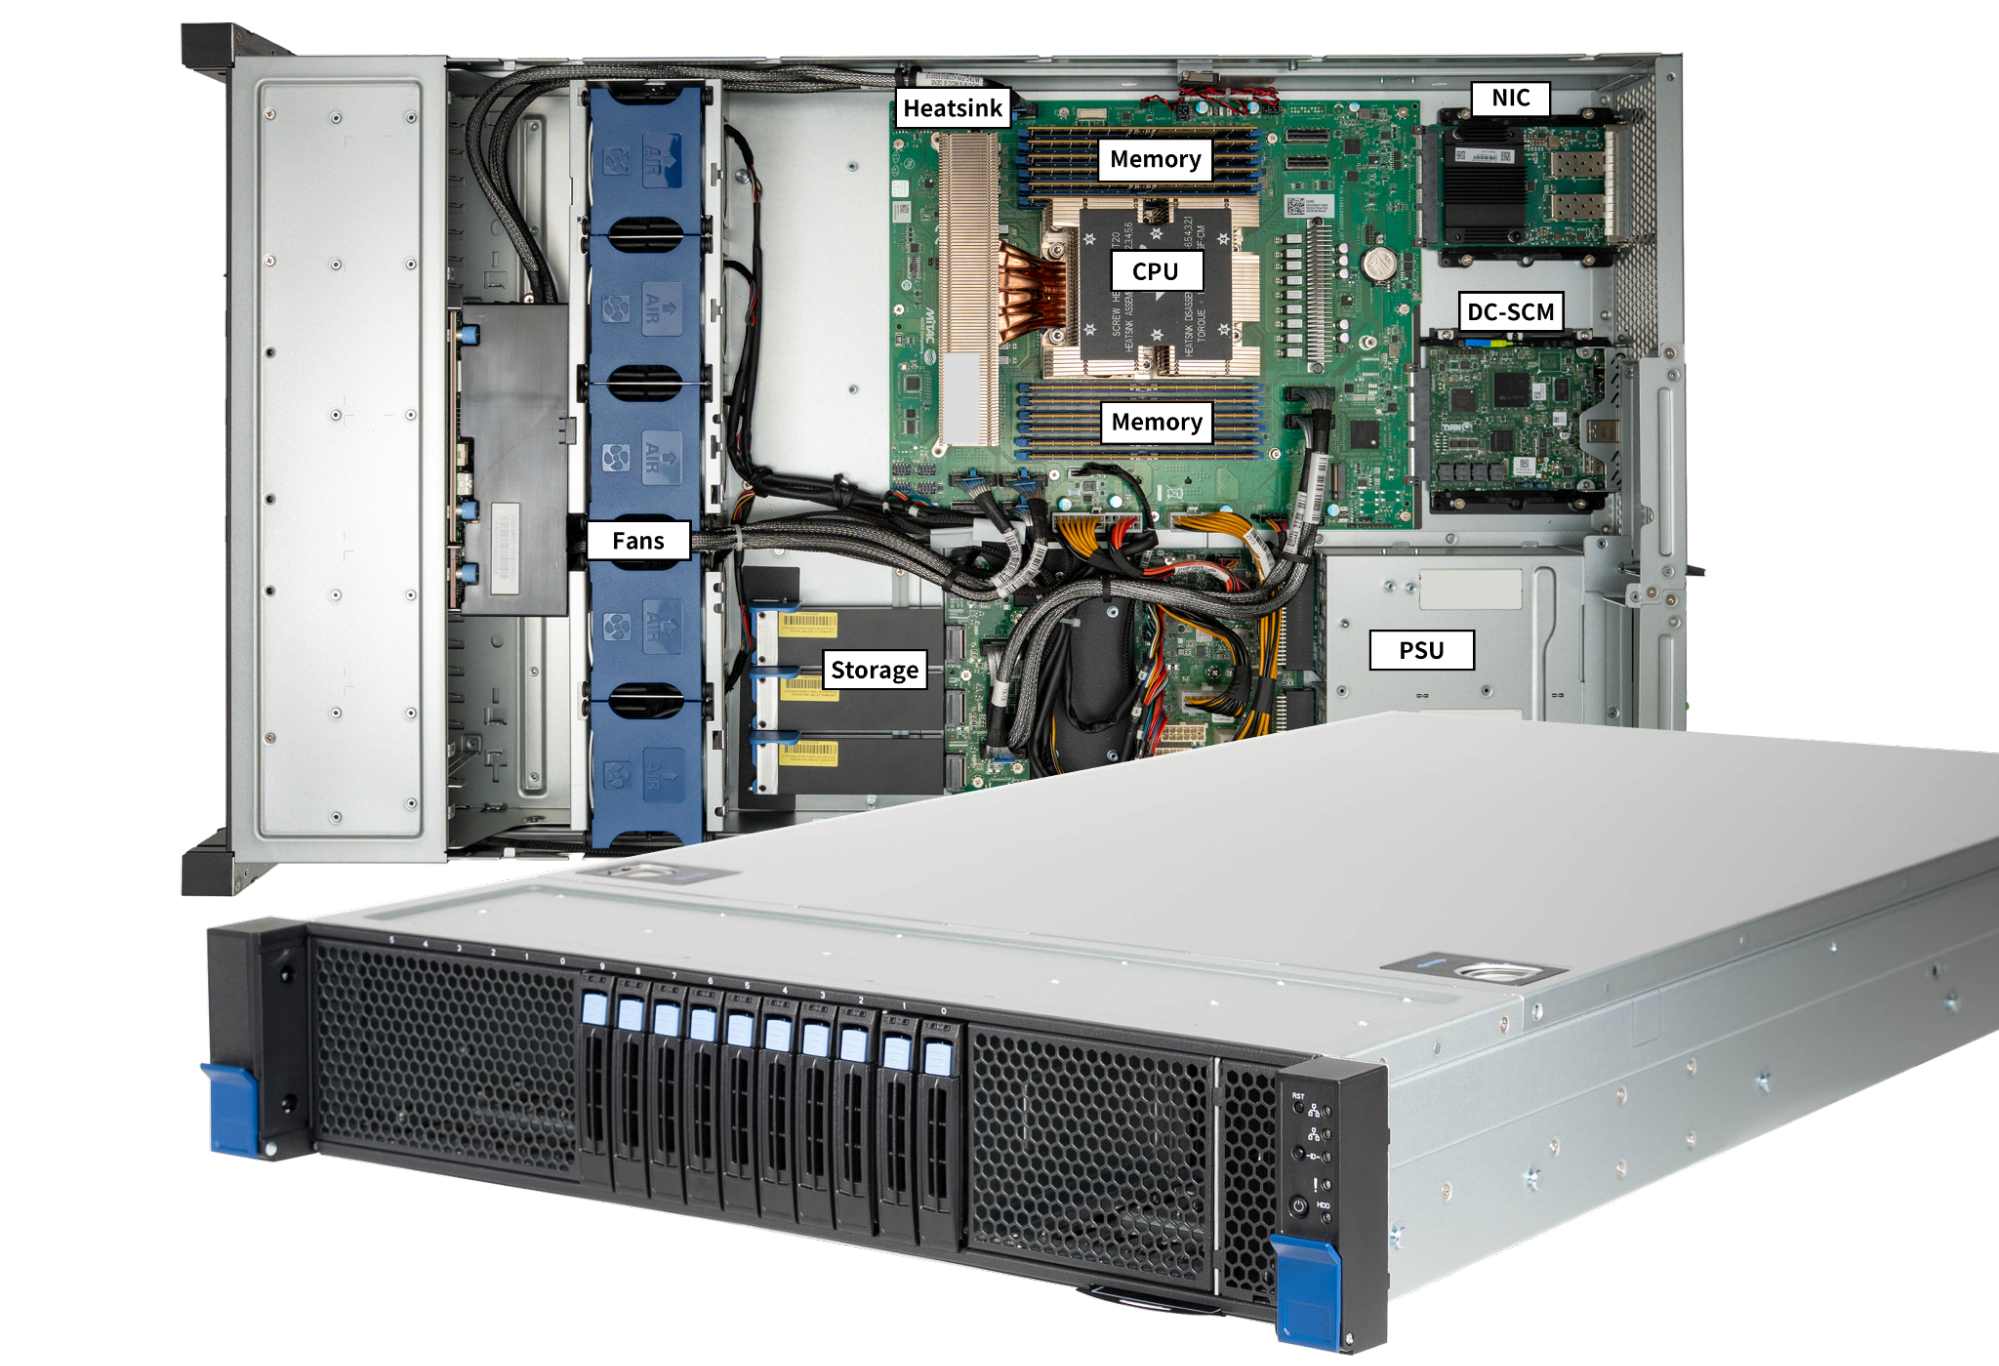
A few months ago, Cloudflare announced the transition to FL2, our Rust-based rewrite of Cloudflare’s core request handling layer. This transition accelerates our ability to help build a better Internet for everyone. With the migration in the software stack, Cloudflare has refreshed our server hardware design with improved hardware capabilities and better efficiency to serve the evolving demands of our network and software stack. Gen 13 is designed with 192-core AMD EPYC™ Turin 9965 processor, 768 GB of DDR5-6400 memory, 24 TB of PCIe 5.0 NVMe storage, and dual 100 GbE port network interface card.
Gen 13 delivers:
Up to 2x throughput compared to Gen 12 while staying within latency SLA
Up to 50% improvement in performance / watt efficiency, reducing data center expansion costs
Up to 60% higher throughput per rack keeping rack power budget constant
The three CPU candidates are designed to target different use cases: AMD Turin 9755 offers superior per-core performance, AMD Turin 9965 trades per-core performance for efficiency, and AMD Turin 9845 trades core count for lower socket power. We evaluated three CPUs in the production environment.
CPU Model
AMD Genoa-X 9684X
AMD Turin 9755
AMD Turin 9845
AMD Turin 9965
For server platform
Gen 12
Gen 13 candidate
Gen 13 candidate
Gen 13 candidate
# of CPU Cores
96
128
160
192
# of Threads
192
256
320
384
Base Clock
2.4 GHz
2.7 GHz
2.1 GHz
2.25 GHz
Max Boost Clock
3.7 GHz
4.1 GHz
3.7 GHz
3.7 GHz
All Core Boost Clock
3.42 GHz
4.1 GHz
3.25 GHz
3.35 GHz
Total L3 Cache
1152 MB
512 MB
320 MB
384 MB
L3 cache per core
12 MB / core
4 MB / core
2 MB / core
2 MB / core
Maximum configurable TDP
400W
500W
390W
500W
Why AMD Turin 9965?
First, FL2 ended the L3 cache crunch.
L3 cache is the large, last-level cache shared among all CPU cores on the same compute die to store frequently used data. It bridges the gap between slow main memory external to the CPU, and the fast but smaller L1 and L2 cache on the CPU, reducing the latency for the CPU to access data.
Some may notice that the 9965 has only 2 MB of L3 cache per core, an 83.3% reduction from the 12 MB per core on Gen 12’s Genoa-X 9684X. Why trade away the very cache advantage that gave Gen 12 its edge? The answer lies in how our workloads have evolved.
Cloudflare has migrated from FL1 to FL2, a complete rewrite of our request handling layer in Rust. With the new software stack, Cloudflare’s request processing pipeline has become significantly less dependent on large L3 cache. FL2 workloads scale nearly linearly with core count, and the 9965’s 192 cores provide a 2x increase in hardware threads over Gen 12.
Second, performance per total cost of ownership (TCO). During production evaluation, the 9965’s 192 cores delivered the highest aggregate requests per second of the three candidates, and its performance-per-watt scaled favorably at 500W TDP, yielding superior rack-level TCO.
Gen 12
Gen 13
Processor
AMD EPYC™ 4th Gen Genoa-X 9684X
AMD EPYC™ 5th Gen Turin 9965
Core count
96C/192T
192C/384T
FL throughput
Baseline
Up to +100%
Performance per watt
Baseline
Up to +50%
Third, operational simplicity. Our operational teams have a strong preference for fewer, higher-density servers. Managing a fleet of 192-core machines means fewer nodes to provision, patch, and monitor per unit of compute delivered. This directly reduces operational overhead across our global network.
Finally,they are forward compatible. The AMD processor architecture supports DDR5-6400, PCIe Gen 5.0, CXL 2.0 Type 3 memory across all SKUs. AMD Turin 9965 has the highest number of high-performing cores per socket in the industry, maximizing the compute density per socket, maintaining competitiveness and relevance of the platform for years to come. By moving to AMD Turin 9965 from AMD Genoa-X 9684X, we get longer security support from AMD, extending the useful life of the Gen 13 server before they become obsolete and need to be refreshed.
Memory
Gen 12
12x 32GB DDR5-4800 2Rx8 (384 GB total, 4 GB/core)
Gen 13
12x 64GB DDR5-6400 2Rx4 (768 GB total, 4 GB/core)
Because the AMD Turin processor has twice the core count of the previous generation, it demands more memory resources, both in capacity and in bandwidth, to deliver throughput gains.
Maximizing bandwidth with 12 channels
The chosen AMD EPYC™ 9965 CPU supports twelve memory channels, and for Gen 13, we are populating every single one of them. We’ve selected 64 GB DDR5-6400 ECC RDIMMs in a “one DIMM per channel” (1DPC) configuration.
This setup provides 614 GB/s of peak memory bandwidth per socket, a 33.3% increase compared to our Gen 12 server platform. By utilizing all 12 channels, we ensure that the CPU is never “starved” for data, even during the most memory-intensive parallel workloads.
Populating all twelve channels in a balanced configuration — equal capacity per channel, with no mixed configurations — is common best practice. This matters operationally: AMD Turin processors interleave across all memory channels with the same DIMM type, same memory capacity and same rank configuration. Interleaving increases memory bandwidth by spreading contiguous memory access across all memory channels in the interleave set instead of sending all memory access to a single or a small subset of memory channels.
The 4 GB per core “sweet spot”
Our Gen 12 servers are configured with 4GB per core. We revisited that decision as we designed Gen 13.
Cloudflare launches a lot of new products and services every month, and each new product or service demands an incremental amount of memory capacity. These accumulate over time and could become an issue of memory pressure, if memory capacity is not sized appropriately.
Initial requirement considered a memory-to-core ratio between 4 GB and 6 GB per core. With 192 cores on the AMD Turin 9965, that translates to a range of 768 GB to 1152 GB. Note that at higher capacities, DIMM module capacity granularity are typically 16GB increments. With 12 channels in a 1DPC configuration, our options are 12x 48GB (576 GB), 12x 64GB (768 GB), or 12x 96GB (1152 GB).
12x 48GB = 576 GB, or 1.5 GB/thread. The memory capacity of this configuration is too low; this would starve memory-hungry workloads and violate the lower bound.
12x 96GB = 1152 GB, or 3.0 GB/thread. This would be a 50% capacity increase per core and would also result in higher power consumption and a substantial increase in cost, especially in the current market conditions where memory prices are 10x of what they were a year ago.
12x 64GB = 768 GB, or 2.0 GB/thread (4 GB/core). This configuration is consistent with our Gen 12 memory to core ratio, and represents a 2x increase in memory capacity per server. Keeping the memory capacity configuration at 4 GB per core provides sufficient capacity for workloads that scale with core count, like our primary workload, FL, and provide sufficient memory capacity headroom for future growth without overprovisioning.
FL2 uses memory more efficiently than FL1 did: our internal measures show FL2 uses less than half the CPU of FL1, and far less than half the memory. The capacity freed up by the software stack migration provides ample headroom to support Cloudflare growth for the next few years.
The decision: 12x 64GB for 768 GB total. This maintains the proven 4 GB/core ratio, provides a 2x total capacity increase over Gen 12, and stays within the DIMM cost curve sweet spot.
Efficiency through dual rank
In Gen 12, we demonstrated that dual-rank DIMMs provide measurably higher memory throughput than single-rank modules, with advantages of up to 17.8% at a 1:1 read-write ratio. Dual-rank DIMMs are faster because they allow the memory controller to access one rank while another is refreshing. That same principle carries forward here.
Our requirement also calls for approximately 1 GB/s of memory bandwidth per hardware thread. With 614 GB/s of peak bandwidth across 384 threads, we deliver 1.6 GB/s per thread, comfortably exceeding the minimum. Production analysis has shown that Cloudflare workloads are not memory-bandwidth-bound, so we bank the headroom as margin for future workload growth.
By opting for 2Rx4 DDR5 RDIMMs at maximum supported 6400MT/s, we ensure we get the lowest latency and best performance from our Gen 13 platform memory configuration.
Storage
Gen 12
x2 E1.S NVMe PCIe 4.0, 16 TB total
Samsung PM9A3 7.68TB
Micron 7450 Pro 7.68TB
Gen 13
x3 E1.S NVMe PCIe 5.0, 24 TB total
Samsung PM9D3a 7.68TB
Micron 7600 Pro 7.68TB
+10x U.2 NVMe PCIe 5.0 option
Our storage architecture underwent a transformation in Gen 12 when we pivoted from M.2 to EDSFF E1.S. For Gen 13, we are increasing the storage capacity and the bandwidth to align with the latest technology. We have also added a front drive bay for flexibility to add up to 10x U.2 drives to keep pace with Cloudflare storage product growth.
The move to PCIe 5.0
Gen 13 is configured with PCIe Gen 5.0 NVMe drives. While Gen 4.0 served us well, the move to Gen 5.0 ensures that our storage subsystem can serve data at improved latency, and keep up with increased storage bandwidth demand from the new processor.
16 TB to 24 TB
Beyond the speed increase, we are physically expanding the array from two to three NVMe drives. Our Gen 12 server platform was designed with four E1.S storage drive slots, but only two slots were populated with 8TB drives. The Gen 13 server platform uses the same design with four E1.S storage drive slots available, but with three slots populated with 8TB drives. Why add a third drive? This increases our storage capacity per server from 16TB to 24TB, ensuring we are expanding our global storage capacity to maintain and improve CDN cache performance. This supports growth projections for Durable Objects, Containers, and Quicksilver services, too.
Front drive bay to support additional drives
For Gen 13, the chassis is designed with a front drive bay that can support up to ten U.2 PCIe Gen 5.0 NVMe drives. The front drive bay provides the option for Cloudflare to use the same chassis across compute and storage platforms, as well as the flexibility to convert a compute SKU to a storage SKU when needed.
Endurance and reliability
We designed our servers to have a 5-year operational life and require storage drives endurance to sustain 1 DWPD (Drive Writes Per Day) over the full server lifespan.
Both the Samsung PM9D3a and Micron 7600 Pro meet the 1 DWPD specification with a hardware over-provisioning (OP) of approximately 7%. If future workload profiles demand higher endurance, we have the option to hold back additional user capacity to increase effective OP.
NVMe 2.0 and OCP NVMe 2.0 compliance
Both the Samsung PM9D3a and Micron 7600 adopt the NVMe 2.0 specification (up from NVMe 1.4) and the OCP NVMe Cloud SSD Specification 2.0. Key improvements include Zoned Namespaces (ZNS) for better write amplification management, Simple Copy Command for intra-device data movement without crossing the PCIe bus, and enhanced Command and Feature Lockdown for tighter security controls. The OCP 2.0 spec also adds deeper telemetry and debug capabilities purpose-built for datacenter operations, which aligns with our emphasis on fleet-wide manageability.
Thermal efficiency
The storage drives will continue to be in the E1.S 15mm form factor. Its high-surface-area design is essential for cooling these new Gen 5.0 controllers, which can pull upwards of 25W under sustained heavy I/O. The 2U chassis provides ample airflow over the E1.S drives as well as U.2 drive bays, a design advantage we validated in Gen 12 when we made the decision to move from 1U to 2U.
Network
Gen 12
Dual 25 GbE port OCP 3.0 NIC
Intel E810-XXVDA2
NVIDIA Mellanox ConnectX-6 Lx
Gen 13
Dual 100 GbE port OCP 3.0 NIC
Intel E830-CDA2
NVIDIA Mellanox ConnectX-6 Dx
For more than eight years, dual 25 GbE was the backbone of our fleet. Since 2018 it has served us well, but as the CPU has improved to serve more requests and our products scale, we’ve officially hit the wall. For Gen 13, we are quadrupling our per-port bandwidth.
Why 100 GbE and why now?
Network Interface Card (NIC) bandwidth must keep pace with compute performance growth. With 192 modern cores, our 25 GbE links will become a measurable bottleneck. Production data from our co-locations worldwide over a week showed that, on our Gen 12, P95 bandwidth per port is consistently >50% of available bandwidth. Since throughput is doubling per server on Gen 13, we are at risk of saturating the NIC bandwidth.
Figure: on Gen 12, P95 bandwidth per port is consistently >50% of available bandwidth
The decision to go to 100 GbE rather than 50 GbE was driven by industry economics: 50 GbE transceiver volumes remain low in the industry, making them a poor supply chain bet. Dual 100 GbE ports also give us 200 Gb/s of aggregate bandwidth per server, future-proofing against the next several years of traffic growth.
Hardware choices and compatibility
We are maintaining our dual-vendor strategy to ensure supply chain resilience, a lesson hard-learned during the pandemic when single-sourcing the Gen 11 NIC left us scrambling.
Both NICs are compliant with OCP 3.0 SFF/TSFF form factor with the integrated pull tab, maintaining chassis commonality with Gen 12 and ensuring field technicians need no new tools or training for swaps.
PCIe Allocation
The OCP 3.0 NIC slot is allocated PCIe 4.0 x16 lanes on the motherboard, providing 256 Gb/s of bidirectional bandwidth, more than enough for dual 100 GbE (200 Gb/s aggregate) with room to spare.
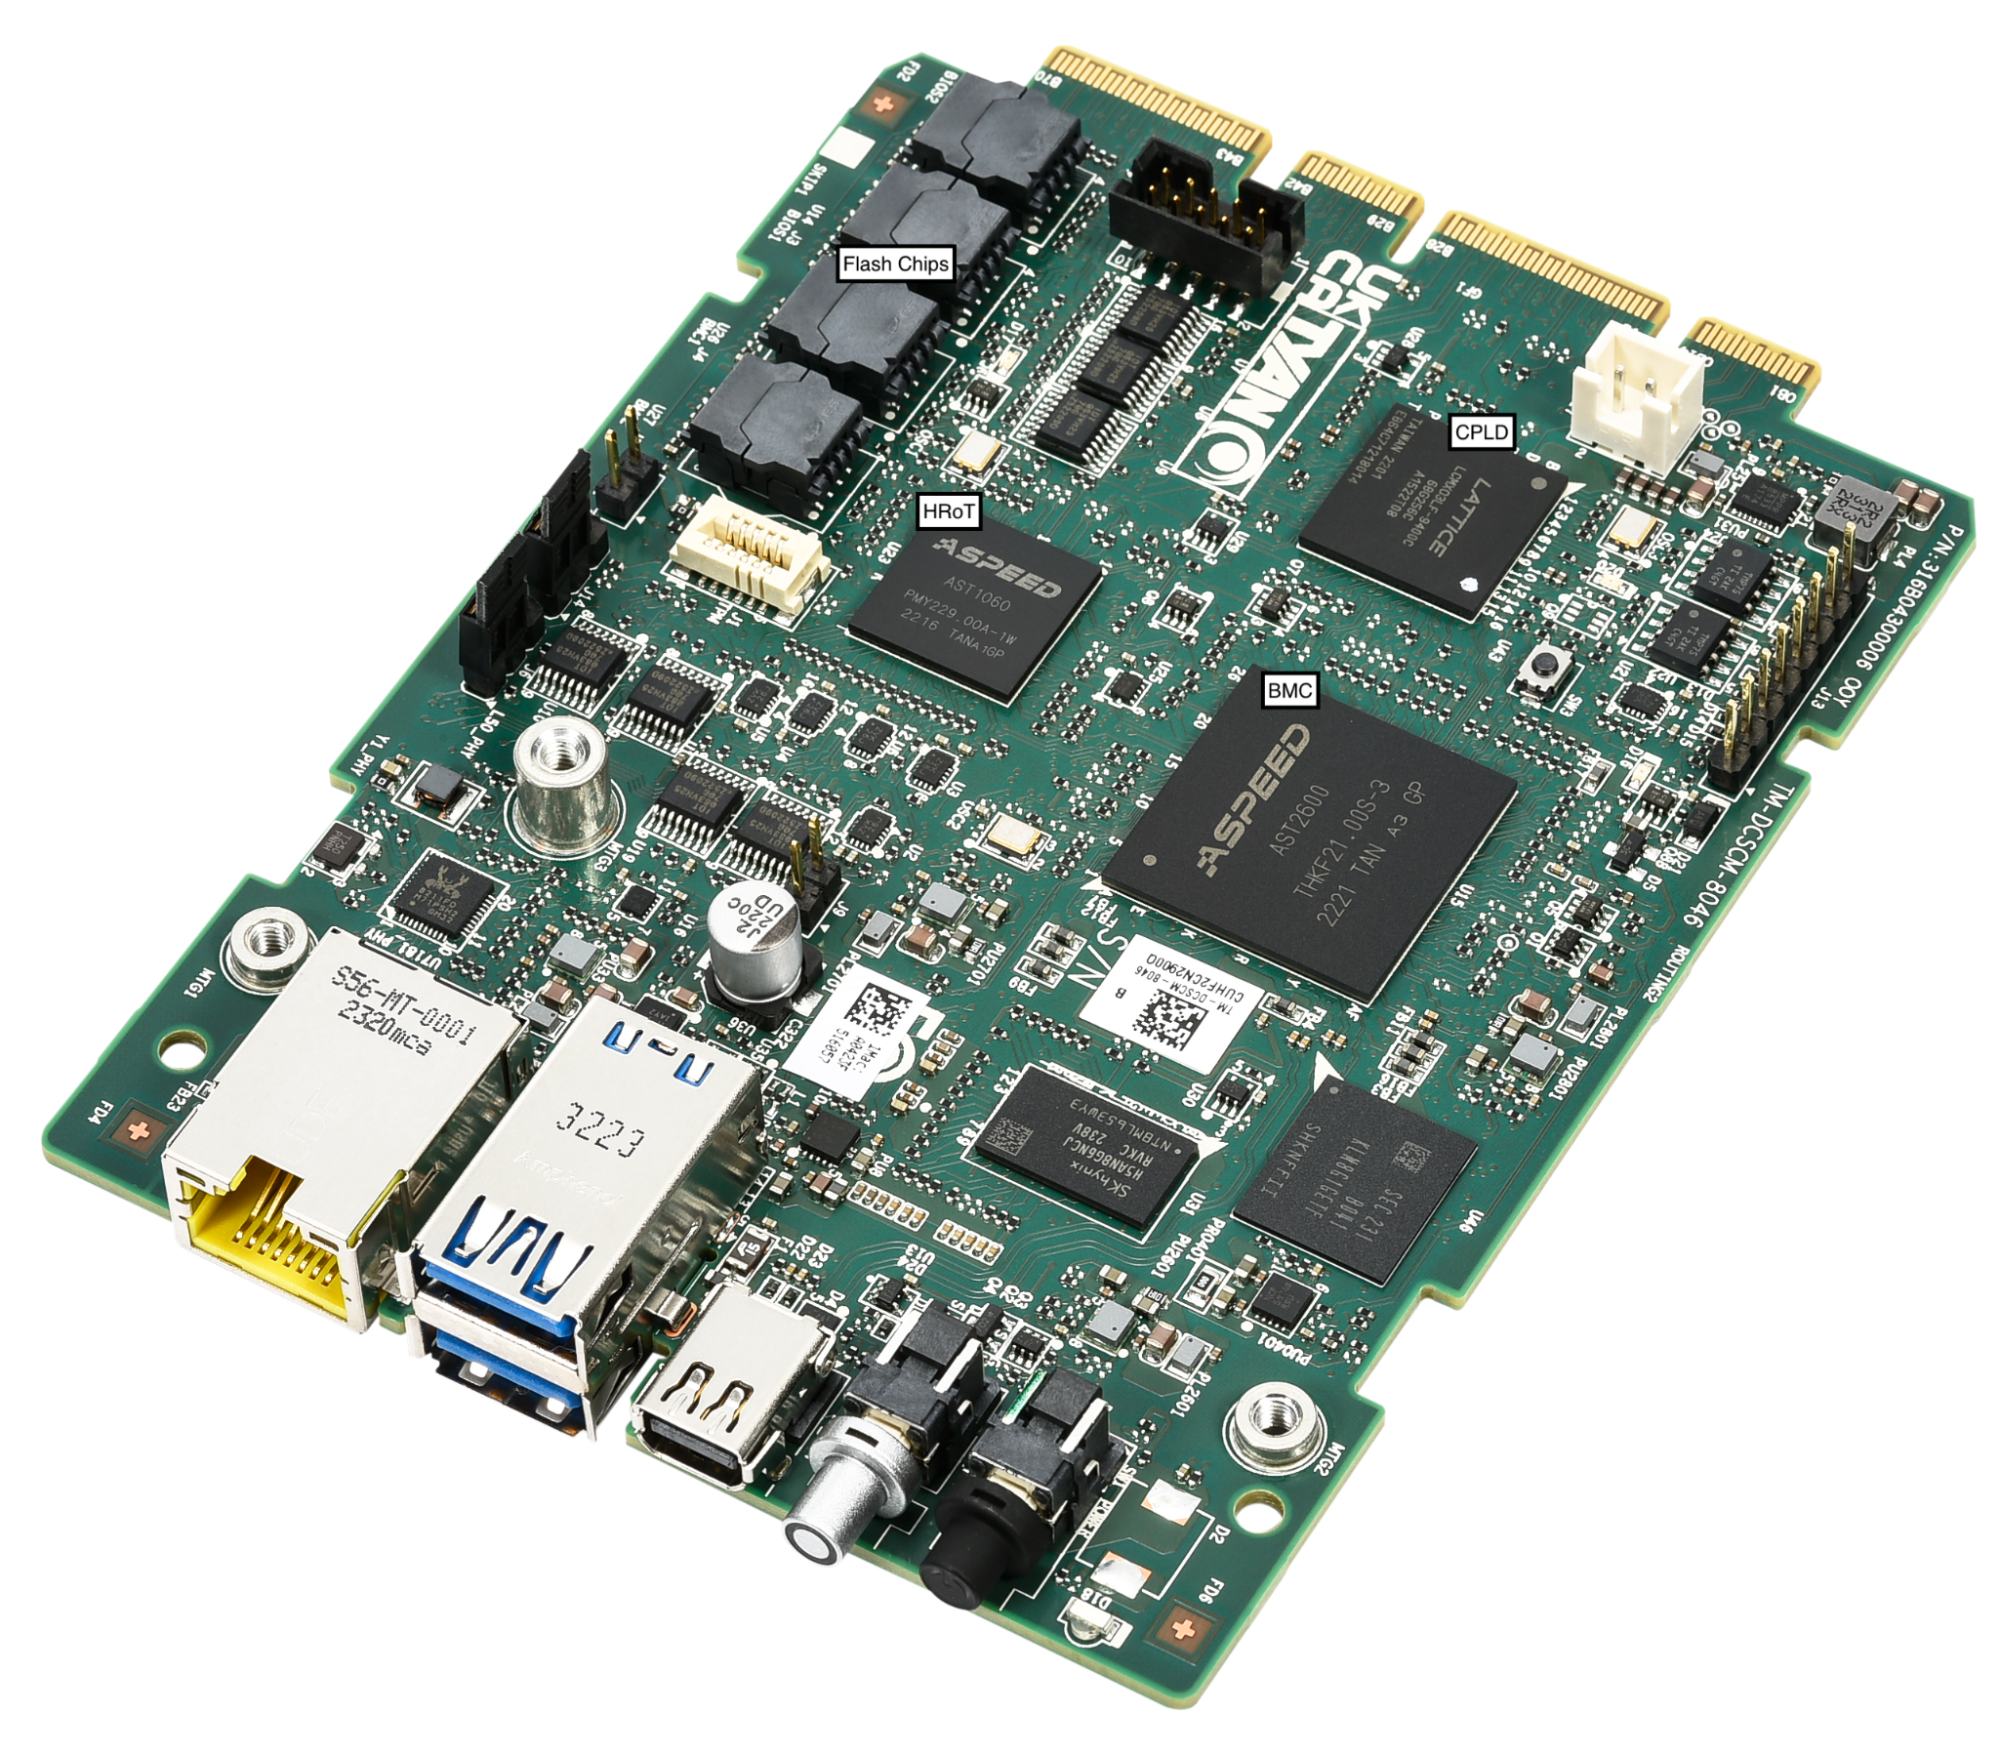
We are maintaining the architectural shift, introduced in Gen 12, of separating management and security-related components from the motherboard onto the Project Argus Data Center Secure Control Module 2.0.
Figure: Project Argus DC-SCM 2.0
Continuity with DC-SCM 2.0
We are carrying forward the Data Center Secure Control Module 2.0 (DC-SCM 2.0) standard. By decoupling management and security functions from the motherboard, we ensure that the “brains” of the server’s security stay modular and protected.
The DC-SCM module houses our most critical components:
Basic Input/Output System (BIOS)
Baseboard Management Controller (BMC)
Hardware Root of Trust (HRoT) and TPM (Infineon SLB 9672)
Dual BMC/BIOS flash chips for redundancy
Why we are staying the course with DC-SCM 2.0
The decision to keep this architecture for Gen 13 is driven by the proven security gains we saw in the previous generation. By offloading these functions to a dedicated module, we maintain:
Rapid recovery: Dual image redundancy allows for near-instant restoration of BIOS/UEFI and BMC firmware if an accidental corruption or a malicious update is detected.
Physical resilience: The Gen 13 chassis also moves the intrusion detection mechanism further from the flat edge of the chassis, making physical intercept harder.
PCIe encryption: In addition to TSME (Transparent Secure Memory Encryption) for CPU-to-memory encryption that was already enabled since our Gen 10 platforms, AMD Turin 9965 processor for Gen 13 extends encryption to PCIe traffic, this ensures data is protected in transit across every bus in the system.
Operational consistency: Sticking with the Gen 12 management stack means our security audits, deployment, provisioning, and operational standard procedure remain fully compatible.
Power
Gen 12
800W 80 PLUS Titanium CRPS
Gen 13
1300W 80 PLUS Titanium CRPS
As we upgrade the compute and networking capability of the server, the power envelope of our servers has naturally expanded. Gen 13 are equipped with bigger power supplies to deliver the power needed.
The jump to 1300W
While our Gen 12 nodes operated comfortably with 800W 80 PLUS Titanium CRPS (Common Redundant Power Supply), the Gen 13 specification requires a larger power supply. We have selected a 1300W 80 PLUS Titanium CRPS.
Power consumption of Gen 13 during typical operation has risen to 850W, a 250W increase over the 600W seen in Gen 12. The primary contributors are the 500W TDP CPU (up from 400W), doubling of the memory capacity and the additional NVMe drive.
Why 1300W instead of 1000W? The current PSU ecosystem lacks viable, high-efficiency options at 1000W. To ensure supply chain reliability, we moved to the next industry-standard tier of 1300W.
EU Lot 9 is a regulation that requires servers deploying in the European Union to have power supplies with efficiency at 10%, 20%, 50% and 100% load to be at or above the percentage threshold specified in the regulation. The threshold matches 80 PLUS Power Supply certification program titanium grade PSU requirement. We chose a titanium grade PSU for Gen 13 to maintain full compliance with EU Lot 9, ensuring that the servers can be deployed in our European data centers and beyond.
Thermal design: 2U pays dividends again
The 2U1N form factor we adopted in Gen 12 continues to pay dividends. Gen 13 uses 5x 80mm fans (up from 4x in Gen 12) to handle the increased thermal load from the 500W CPU. The larger fan volume, combined with the 2U chassis airflow characteristics, means fans operate well below maximum duty cycle at typical ambient temperatures, keeping fan power in the < 50W range per fan.
Drop-in accelerator support
Gen 12
x2 single width FHFL or x1 double width FHFL
Gen 13
x2 double width FHFL
Maintaining the modularity of our fleet is a core requirement for our server design. This requirement enabled Cloudflare to quickly retrofit and deploy GPUs globally to more than 100 cities in 2024. In Gen 13, we are continuing the support of high-performance PCIe add-in cards.
On Gen 13, the 2U chassis layout is updated and configured to support more demanding power and thermal requirements. While Gen 12 was limited to a single double-width GPU, the Gen 13 architecture now supports two double-width PCIe cards.
A launchpad to scale Cloudflare to greater heights
Every generation of Cloudflare servers is an exercise in balancing competing constraints: performance versus power, capacity versus cost, flexibility versus simplicity. Gen 13 comes with 2x core count, 2x memory capacity, 4x network bandwidth, 1.5x storage capacity, and future-proofing for accelerator deployments — all while improving total cost of ownership and maintaining a robust management feature set and security posture that our global fleet demands.
Gen 13 servers are fully qualified and will be deployed to serve millions of requests across Cloudflare’s global network in more than 330 cities. As always, Cloudflare’s journey to serve the Internet as efficiently as possible does not end here. As the deployment of Gen 13 begins, we are planning the architecture for Gen 14.
If you are excited about helping build a better Internet, come join us. We are hiring.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.