Post Syndicated from Nicolo Cosimo Albanese original https://aws.amazon.com/blogs/architecture/agentic-antimicrobial-resistance-surveillance-with-aws-healthomics-and-amazon-bedrock-agentcore/
Turn public sequencing data into plain-language answers about resistance genes, without writing bioinformatics code or SQL.
Bacterial antimicrobial resistance (AMR) is one of the top public health threats of our time. A systematic analysis published in The Lancet estimated that AMR was directly responsible for 1.27 million deaths in 2019 and associated with 4.95 million (Murray et al., 2022). Surveillance programs work to slow that trend by tracking which resistance genes circulate, in which organisms, and how the picture shifts over time.
The raw material for that work is already public. Sequencing archives such as the NCBI Sequence Read Archive (SRA) hold hundreds of thousands of bacterial whole-genome sequencing runs, and the data is mirrored on the Registry of Open Data on AWS. The constraint isn’t access to data. It’s the work of turning a raw sequencing run into an answer. That path normally means assembling a genome, screening it for resistance genes with specialized tools, loading the results into an analytical store, and writing SQL to explore them. Each step assumes bioinformatics skills, so the people who ask the epidemiological questions often depend on a specialist to answer them.
In this post, we present a reference architecture that shortens that path. A researcher signs in to a web application, submits a public SRA accession, and after the pipeline finishes asks, in plain language, “What AMR genes were found in Salmonella?” The system answers with the genes detected, the tool that found each one, and a confidence value taken from the data. The architecture is defined entirely in AWS Cloud Development Kit (AWS CDK) and deploys into an account with a single command. This is a demonstration architecture rather than a clinical system, and the accompanying code is available for you to deploy and adapt.
How this architecture differs from variant interpretation
An earlier AWS post, Accelerating genomics variant interpretation with AWS HealthOmics and Amazon Bedrock AgentCore, established a pattern that this solution shares: a genomics pipeline feeds Amazon S3 Tables, a capability of Amazon Simple Storage Service (Amazon S3), in Apache Iceberg format, Amazon Athena queries the tables, and a Strands agent on Amazon Bedrock AgentCore turns questions into SQL. We reuse that querying pattern rather than reinvent it. What’s different here is the genomics problem and the shape of the pipeline around it.
The variant interpretation solution starts from a Variant Call Format (VCF) file, where variants have already been called, and annotates them. This solution starts a step earlier, from raw sequencing reads, and performs read quality control, de novo assembly, and gene detection before results exist to store. It adds an ingestion stage that pulls reads directly from a public archive and deduplicates work across runs, and it merges detection output into Iceberg idempotently so that reprocessing an isolate updates its rows in place. Those differences, public-data ingestion, assembly-based detection, and idempotent storage, are where the engineering effort of this architecture sits.
Solution overview
The solution is a set of loosely coupled stages, and data moves in one direction from ingestion through processing and storage to a conversational query layer. The following stages map to the numbered zones in Figure 2.
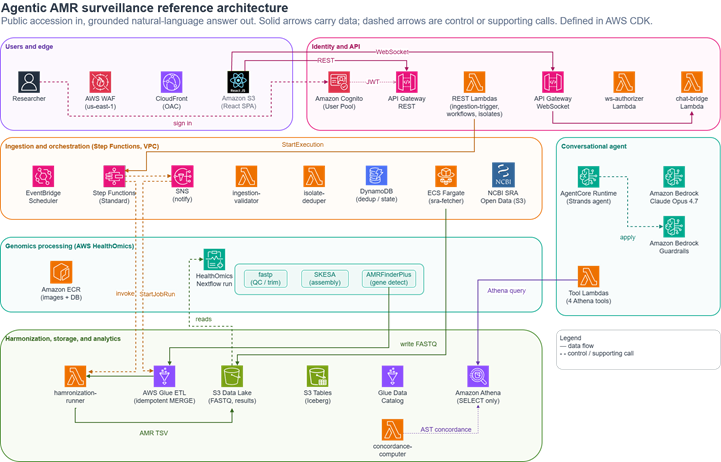
Figure 2: Solution architecture, organized as the five stages the data passes through
- Ingestion: An Amazon EventBridge Scheduler rule or an on-demand REST call starts an AWS Step Functions workflow. An Amazon Elastic Container Service (Amazon ECS) task on AWS Fargate fetches and converts the sequencing run for the requested accession from the NCBI SRA mirror on the Registry of Open Data, and Amazon DynamoDB records processed isolates so that repeat runs skip work that’s already done.
- Genomics processing: AWS HealthOmics runs a single managed Nextflow workflow that chains read quality control with fastp, de novo assembly with SKESA, and resistance gene detection with AMRFinderPlus. Container images come from Amazon Elastic Container Registry (Amazon ECR), and the AMRFinderPlus reference database is built into the image because HealthOmics tasks run without internet access.
- Harmonization and storage: An AWS Lambda function normalizes the detection output into the community hAMRonization schema (a standard from PHA4GE for reporting AMR detection results), and an AWS Glue job merges it into Iceberg tables on Amazon S3 Tables. The merge is idempotent, so rerunning an isolate updates rows rather than duplicating them.
- Analytical store: Amazon Athena queries the Iceberg tables through the AWS Glue Data Catalog, which gives the agent a fast SQL surface over the harmonized results.
- Conversational agent and web application: A Strands agent hosted on AgentCore runtime answers questions through a set of Athena-backed tools, with Amazon Bedrock Guardrails keeping responses grounded. A React single-page application on Amazon S3 and Amazon CloudFront, protected by AWS WAF and authenticated with Amazon Cognito, is the front door. Amazon API Gateway serves REST calls and streams the chat over WebSocket.
Ingesting public sequencing data
Ingestion has one job: given an accession, get the reads into the account without manual downloads or credentials. Because the SRA mirror is part of the Registry of Open Data, an anonymous Amazon S3 read is enough. A Step Functions workflow drives the process. It starts a Fargate task that downloads the sequencing run for the accession from the public bucket and converts it to paired-end FASTQ in a staging bucket, then hands off to the genomics stage.
Two design choices keep the stage predictable. A DynamoDB table records every isolate that has been processed, so a scheduled weekly run or a repeated manual submission doesn’t reprocess the same accession. Fargate runs the copy as a long-running task because fetching and converting a large sequencing run can take well beyond a few minutes. The result is a loop that runs on a schedule or on demand from the web application, without an operator in the middle.
Detecting resistance genes with AWS HealthOmics
Turning reads into a list of resistance genes is the compute-heavy part of the pipeline. AWS HealthOmics runs Nextflow workflows without a cluster to provision or scale, which suits teams that do not run a bioinformatics system of their own.
The workflow is a single HealthOmics run with three tasks connected by Nextflow channels. fastp trims adapters and low-quality bases from the raw reads. SKESA assembles the trimmed reads into contigs. AMRFinderPlus screens those contigs for known resistance genes. Combining assembly and screening in one run avoids a fragile handoff between two separate runs and matches how community AMR pipelines are structured.
Running third-party bioinformatics tools on HealthOmics calls for a few adaptations worth stating plainly:
- HealthOmics tasks have no internet access, so the AMRFinderPlus database is baked into the container image rather than downloaded at runtime.
- Container image URIs are passed as workflow parameters instead of hardcoded, which keeps the workflow independent of account and AWS Region and lets HealthOmics verify image access before a run starts.
- Task outputs are published to the run output path that HealthOmics exports to Amazon S3, rather than to arbitrary locations.
Each container image is built from official tool releases with pinned versions and scanned with Amazon ECR image scanning, so the pipeline doesn’t depend on a floating latest tag.
Harmonizing and storing results
AMRFinderPlus emits a tab-separated file per isolate, which is awkward to analyze across many samples. A Lambda function first normalizes that output into the hAMRonization schema. An AWS Glue job then reshapes the harmonized data into two Iceberg tables on Amazon S3 Tables: amr_profiles, with one row per detected gene, and isolate_metadata, with one row per isolate carrying its provenance and license.
The AWS Glue job writes with a MERGE keyed on the isolate and gene, so processing the same isolate twice updates the existing rows instead of appending duplicates. That idempotency matters for surveillance, where the same accession can arrive again through a scheduled run, and it keeps the tables consistent without a separate deduplication step. Storing the results as Iceberg gives the agent a columnar, transactional surface to query with low latency, and because Amazon S3 Tables registers the schema in the AWS Glue Data Catalog, Athena reads the same tables without extra setup. Converting per-sample files into a structured store is what makes conversational querying across the whole corpus possible.
Asking questions in natural language
The conversational layer uses the Strands Agents SDK and runs on Amazon Bedrock AgentCore, a platform to build, connect, and optimize agents at scale, with any framework or model. This solution uses AgentCore runtime, its serverless agent-hosting environment. It gives each user session an isolated environment, integrates with AWS Identity and Access Management (IAM), and traces the agent’s reasoning and tool calls. The team runs the agent without managing servers or scaling logic.
The agent reasons over four tools, and each one turns a natural-language request into a targeted Athena query against the Iceberg tables:
query_amr_profilesfinds resistance genes for an organism over an optional date range.get_resistance_trendssummarizes how gene detections trend month over month.compare_isolatescompares resistance profiles across isolates.lookup_gene_inforeturns detail on a specific resistance gene.
Grounding is enforced in two places. The system prompt requires the agent to cite the gene ID, the detecting tool, and a confidence value for every claim. It must also say plainly when no data supports an answer rather than guess. Amazon Bedrock Guardrails add a second layer, with a contextual grounding check and denied topics that keep responses tied to the returned rows and off medical or patient advice. The agent uses Anthropic Claude Opus 4.7 on Amazon Bedrock, invoked through a cross-Region inference profile, for the reasoning and synthesis those rules depend on. Model availability varies by AWS Region. See the Amazon Bedrock model support by Region documentation for current availability.
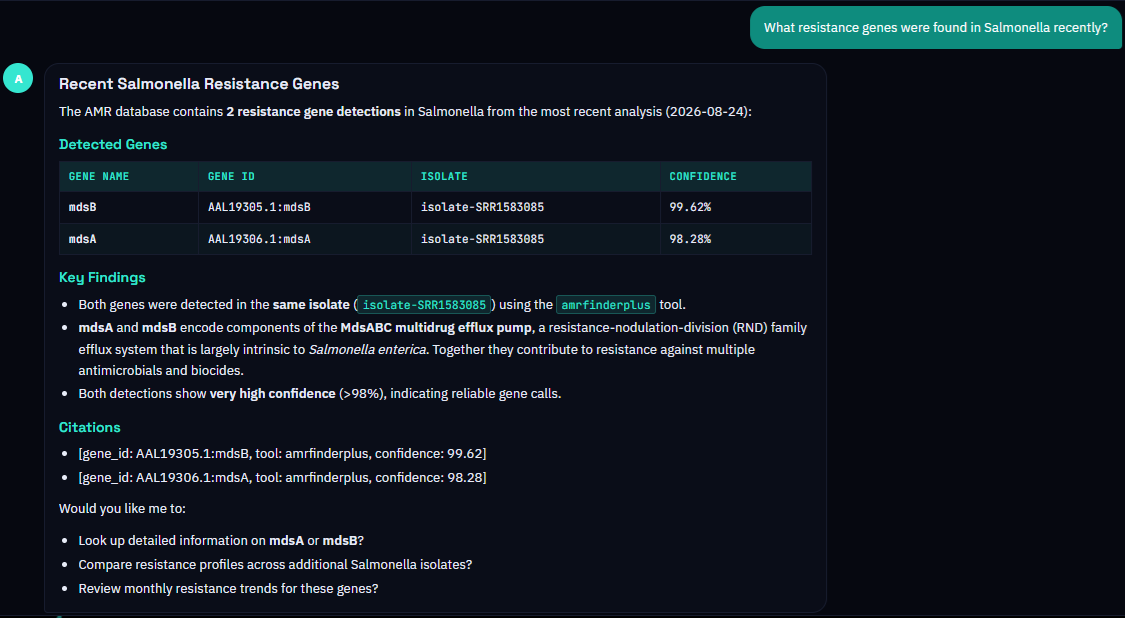
After an isolate has been processed, a researcher explores it through conversation instead of SQL. Asked “What AMR genes were found in Salmonella?”, the agent calls query_amr_profiles, retrieves the matching rows from Iceberg through Athena, and replies with the detected genes. Each gene is annotated with the detecting tool and its confidence value, along with a short reading of what the genes represent. A follow-up such as “Tell me more about mdsB” triggers lookup_gene_info without the user thinking about tables or queries.
Benefits
The architecture turns four recurring pain points into managed, repeatable steps.
| Challenge | How the architecture addresses it |
| Fetching and assembling public sequencing data by hand | A Step Functions workflow pulls reads from the AWS Open Data SRA mirror and runs assembly and screening on managed HealthOmics compute. |
| Reconciling detection output across many samples | A Lambda function harmonizes results and AWS Glue merges them idempotently into Iceberg tables on Amazon S3 Tables. |
| SQL and bioinformatics skills needed to ask a question | A Strands agent on AgentCore turns plain-language questions into Athena queries and answers with cited evidence. |
| Reproducing the environment in another account | The solution is defined in AWS CDK with no hardcoded identifiers, so it deploys with a single command. |
Because this is a reference architecture rather than a customer deployment, its proof is that anyone can stand it up. The CDK application provisions every component described here, from the ingestion workflow to the Iceberg tables to the agent runtime and the web front end. It needs no hardcoded account identifiers or manual setup steps. Running costs depend on how many isolates you process and how often, because HealthOmics runs, AWS Glue jobs, and agent calls are billed per use. The architecture stays inexpensive when idle.
Conclusion
Pairing AWS HealthOmics for managed genomics processing with Amazon Bedrock AgentCore for grounded interpretation lets a surveillance team move from a public accession number to an answer about resistance genes in one continuous flow. Assembly, gene detection, harmonization, and storage happen without manual steps, and the analytical layer is reached through a conversation rather than a query console. The pattern reuses the S3 Tables and agent querying approach from earlier work and applies it to a different genomics problem. That problem begins at raw reads and depends on public-data ingestion and idempotent storage.
To go deeper, see the AWS HealthOmics and Amazon Bedrock AgentCore product pages, and the related post Accelerating genomics variant interpretation with AWS HealthOmics and Amazon Bedrock AgentCore.
The solution is defined entirely in AWS CDK and deploys into your own account. Explore the accompanying repository on GitHub and adapt the pattern to your own surveillance and life-sciences use cases.


