All posts by Yashika Jain

Optimize consumer rebalancing on Amazon MSK with next generation protocol

Post Syndicated from Yashika Jain original https://aws.amazon.com/blogs/big-data/optimize-consumer-rebalancing-on-amazon-msk-with-next-generation-protocol/

If you run large consumer groups on Apache Kafka and Amazon Managed Streaming for Apache Kafka (Amazon MSK), you’ve likely experienced the pain of slow rebalances: processing stalls across all consumers, “rebalance storms” triggered by routine scaling events, and prolonged recovery times that impact downstream applications. With the classic rebalance protocol, even a single consumer joining or leaving the group forces a global synchronization barrier, pausing every consumer regardless of whether its partition assignments changed.

The KIP-848 consumer protocol, introduced in Apache Kafka 4.0, fundamentally redesigns how consumer group rebalancing works. Also referred to as “the Next Generation Consumer Rebalance Protocol”, KIP-848 shifts coordination logic from the client to the broker-side group coordinator. This supports fully incremental, server-driven rebalancing that significantly improves performance for large consumer groups. You can use the consumer protocol on Amazon MSK on all 4.x Apache Kafka versions on both MSK Standard and Express brokers.

In this post, we explain how the consumer protocol works, how to enable it on Amazon MSK, and how to diagnose and resolve slow rebalancing issues to help improve performance.

The classic protocol compared to the consumer protocol

The classic protocol relied on client-side rebalance logic with a global synchronization barrier. Every rebalance caused all consumers in the group to pause processing simultaneously regardless of whether their partition assignments were changing. This led to “rebalance storms” in large consumer groups where cascading rebalances could take minutes to resolve. The CooperativeStickyAssignor is a client-side partition assignment strategy that supports incremental, cooperative rebalancing. It significantly improves rebalance performance and minimizes disruption to groups during rebalance events. However, it still suffers from bottlenecks as consumer group size and partition count increase. For large workloads, client-side rebalancing behavior can result in longer rebalancing times and require significant client tuning and monitoring during rebalances.

The consumer protocol addresses these limitations by moving all rebalancing logic to the server. The broker handles coordination using a continuous heartbeat mechanism and server-driven reconciliation process. Only affected partitions move during a rebalance, and consumers with unchanged assignments continue processing uninterrupted. This results in faster recovery compared to the classic protocol, and improved scalability as workloads grow.

The following table compares the classic and next generation protocols across key dimensions.

Aspect Classic Protocol Next Generation Protocol (KIP-848)
Rebalance logic Client-side Fully server-driven
Consumer impact Depends on assignor, all consumers pause, or rebalance is limited by group size Only affected consumers impacted, scales effectively as groups grow
Mechanism Client-side algorithm and cross-group coordination Incremental, async reconciliation
Commit processing Paused during rebalance Able to progress during rebalance
Scalability Complex, fragile at scale Resilient, broker-driven
Rebalance storms Common in large groups Eliminated

Server-side configuration

With the consumer protocol, key parameters are now configured on the server rather than the client:

  • group.consumer.heartbeat.interval.ms – Controls the consumer heartbeat interval (server-side).
  • group.consumer.session.timeout.ms – Controls the session timeout (server-side).
  • group.consumer.assignors – Specifies available assignors (uniform and range by default).

In Amazon MSK Express brokers, these configurations are read-only and cannot be modified. In Amazon MSK Standard brokers, these configurations are managed with broker configurations. To update these configurations in Amazon MSK Standard brokers, refer to Update the configuration of an Amazon MSK cluster.

When to use the consumer protocol

The consumer protocol provides the most benefit to workloads with the following requirements:

  • Large consumer groups: Groups with many consumers and partitions see the most significant improvements because of the elimination of global synchronization barriers.
  • High-availability applications: Applications that cannot afford processing interruptions benefit from continuous message processing during rebalances. Financial services, real-time analytics, and fraud detection systems are ideal candidates.
  • Frequently rebalancing environments: Automatic scaling deployments, Kubernetes with frequent pod restarts, or continuous integration and continuous delivery (CI/CD) environments experience significantly less disruption.
  • Dynamic partition scaling: Workloads that regularly add partitions or topics benefit from the incremental, server-driven approach.

Prerequisites

Before you begin, make sure that you have the following:

  • An Amazon MSK cluster running Apache Kafka version 4.0 or later (both MSK Standard and Express brokers are supported).
  • A Kafka client library that supports the KIP-848 consumer protocol (see Step 4 for supported versions).
  • Basic familiarity with Apache Kafka consumer groups and partition assignment.
  • An AWS account with appropriate permissions to manage your MSK cluster.

Enabling the consumer protocol on Amazon MSK

The following steps walk you through verifying your cluster version, configuring your consumer client, removing deprecated configurations, and confirming client library support.

Step 1: Verify cluster version

The consumer protocol requires Apache Kafka 4.0 or later. To use the consumer protocol on Amazon MSK, verify that your cluster is running Apache Kafka version 4.0.x or later. You can verify your cluster’s Apache Kafka version using the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS SDKs:

aws kafka describe-cluster-v2 --cluster-arn <your-cluster-arn> \
    --query "ClusterInfo.Provisioned.CurrentBrokerSoftwareInfo.KafkaVersion"

If your cluster is running Apache Kafka 4.0.x or later, the consumer protocol is automatically enabled on the server and ready to use. No additional server-side feature flag verification is needed.

Step 2: Configure consumer client

Set group.protocol=consumer in your consumer configuration. The protocol is not enabled by default:

# confluent-kafka-python example
config = {
    'bootstrap.servers': bootstrap_servers,
    'group.id': group_id,
    'group.protocol': 'consumer',  # Required — defaults to 'classic' if omitted
    'auto.offset.reset': 'earliest'
}

The consumer protocol can be changed in-place for existing consumer groups. When you update the group.protocol, perform a rolling restart of your consumers. The broker-side group coordinator automatically handles the upgrade to the consumer protocol and handles classic protocol requests from old clients alongside the upgraded clients.

Step 3: Remove deprecated client configurations

When the consumer protocol is enabled, the following client-side configurations are no longer supported because they are controlled by the brokers:

  • heartbeat.interval.ms.
  • session.timeout.ms.
  • partition.assignment.strategy.

Step 4: Verify client library support

Verify that your Kafka client version supports the consumer protocol:

  • Java clients: Generally available (GA) in Apache Kafka 4.0+.
  • confluent-kafka-python: Version 2.12.0+ (GA support for KIP-848). See the release notes.
  • librdkafka-based clients (Go, .NET, C/C++): Based on librdkafka 2.12.0+.

Note: For other Kafka client libraries, verify your client library’s documentation for group.protocol=consumer support before enabling the next generation protocol. If your client doesn’t support KIP-848, it will continue to use the classic protocol.

Diagnosing slow consumer group rebalancing with the consumer protocol

Even after enabling the consumer protocol, you may encounter situations where consumer group rebalancing takes longer than expected. The following sections help you diagnose and resolve these issues.

Common symptoms

  • Consumer group rebalancing takes longer than expected despite setting group.protocol=consumer.
  • Consumers pause processing during rebalances.
  • Broker logs show “member session expired” or “fenced” messages.
  • Frequent rebalances triggered during rolling deployments or pod restarts.

Step 1: Confirm the consumer protocol is active using broker logs

Before troubleshooting performance, verify which protocol your consumers are actually using. Check broker logs in Amazon CloudWatch Logs Insights. The log patterns differ significantly between protocols.

Consumer protocol expected logs:

Key indicators: “consumer protocol”, “epoch” terminology, “target assignment” with server-side assignor, “fenced” for member removal.

[GroupCoordinator id=X] [GroupId <group-id>] Member <member-id> joins the consumer group using the consumer protocol.
[GroupCoordinator id=X] [GroupId <group-id>] Bumped group epoch to 309 with metadata hash 4064309670987706693.
[GroupCoordinator id=X] [GroupId <group-id>] Computed a new target assignment for epoch 309 with 'uniform' assignor in 0ms.
[GroupCoordinator id=X] [GroupId <group-id>] Member <member-id> fenced from the group because the member session expired.

Classic protocol expected logs:

Key indicators: “PreparingRebalance” state, “old generation” terminology, “Assignment received from leader”.

If you see classic protocol logs, the consumer protocol is not active. Proceed to Step 2 to troubleshoot why.

[GroupCoordinator id=X] Preparing to rebalance group <group-id> in state PreparingRebalance with old generation X
[GroupCoordinator id=X] Stabilized group <group-id> with X members
[GroupCoordinator id=X] Assignment received from leader for group <group-id>

Step 2: Troubleshoot why the consumer protocol is not active

Verify that your client configuration, client library versions, and cluster versions support the consumer protocol, as described in the preceding Step 1 through Step 4.

Step 3: Resolve slow rebalancing when KIP-848 is active

After you verify the consumer protocol is active but rebalancing is still slow, investigate the following causes:

A. Consumer session timeout causing premature member removal

With the consumer protocol, session timeout is server-controlled through group.consumer.session.timeout.ms (default: 45 seconds). The diagnostic path depends on whether you are using static group membership. The following table outlines the diagnostic path and recommended actions for each scenario.

Scenario Symptom Root cause Recommended action
With static group membership (group.instance.id configured) Slow rebalancing when a static member terminates without calling consumer.close() The coordinator waits for the full session timeout before reassigning partitions. This is the most common cause of slow rebalancing in containerized environments. MSK Standard: Implement graceful shutdown to trigger an immediate leave-group request, or increase the session timeout: group.consumer.session.timeout.ms=60000 (default is 45000). MSK Express: This configuration is not editable in Amazon MSK Express clusters. For Amazon MSK Express, optimize your client’s cold starts to allow members to restart within the 45 second consumer session timeout.
Without static group membership Session timeouts expiring during normal operations Your consumer is freezing or becoming unresponsive, which prevents heartbeats from reaching the coordinator.

Investigate long-running message processing, garbage collection pauses, network connectivity issues, or resource exhaustion on the consumer host. Look for this in broker logs:

[GroupCoordinator id=X] [GroupId <group-id>] Member <member-id> has timed out

B. Missing graceful shutdown handling

When consumers terminate without calling consumer.close(), the coordinator waits for the full session timeout before removing the member. This is the most common cause of slow rebalancing in containerized environments.

Resolution: Implement proper SIGTERM handling to trigger an immediate leave-group:

import signal
import sys
from confluent_kafka import Consumer

class GracefulKafkaConsumer:
    def __init__(self, config):
        self.running = True
        self.consumer = Consumer(config)
        signal.signal(signal.SIGTERM, self.shutdown_handler)
        signal.signal(signal.SIGINT, self.shutdown_handler)

    def shutdown_handler(self, signum, frame):
        print(f"Received signal {signum}, initiating graceful shutdown...")
        self.running = False

    def consume_loop(self):
        self.consumer.subscribe(['your-topic'])
        while self.running:
            msg = self.consumer.poll(timeout=1.0)
            if msg is None:
                continue
            # Process message

        print("Closing consumer gracefully...")
        self.consumer.close()  # Sends LeaveGroup — triggers immediate rebalance
        sys.exit(0)

For Kubernetes, verify that terminationGracePeriodSeconds allows time for consumer.close() to complete:

spec:
  terminationGracePeriodSeconds: 60
  containers:
    - name: kafka-consumer

C. Frequent rebalances from unstable consumers

If consumers repeatedly join and leave (out-of-memory (OOM) kills, CrashLoopBackOff, or short-lived tasks), each event triggers a new rebalance epoch.

Resolution: Use static membership by assigning a unique group.instance.id:

config = {
    'bootstrap.servers': bootstrap_servers,
    'group.id': 'my-group',
    'group.protocol': 'consumer',
    'group.instance.id': f'consumer-{unique_identifier}'  # Unique per consumer
}

With static membership:

  • Short restarts within the session timeout don’t trigger rebalances.
  • The consumer rejoins with the same partition assignment.
  • Scaling up (adding new consumers) still works. New group.instance.id values trigger assignment of unassigned partitions only.

Monitoring and validation

After applying changes, confirm the improvement:

  • Check broker logs: Confirm that “member session expired” messages no longer appear during normal operations or deployments.
  • Monitor consumer lag: Use the SumOffsetLag and EstimatedMaxTimeLag Amazon CloudWatch metrics to verify that lag returns to zero quickly after a rebalance.
  • Describe consumer group: Use kafka-consumer-groups.sh --describe to verify that all members are active and stable.

Conclusion

After implementing the consumer protocol, you should observe the following behavior for consumer group rebalances:

  • Consistently faster rebalance times compared to the classic protocol.
  • Fewer session timeout-related rebalances.
  • More stable consumer group membership.
  • Smooth scaling operations without disrupting existing consumers.
  • Fewer unnecessary rebalances during consumer restarts when using static membership.
  • Clean consumer departures without waiting for timeout expiration when using graceful shutdown.

To get started, try the consumer protocol in your non-production workloads and observe the rebalance improvements as you scale your workload up and down.

To learn more about Amazon MSK and the consumer rebalance protocol, see the following resources:


About the authors

Yashika Jain

Yashika Jain

Yashika is a Senior Cloud Analytics Engineer at AWS, specializing in real-time analytics and event-driven architectures. She is committed to helping customers by providing deep technical guidance, driving best practices across real-time data platforms and solving complex issues related to their streaming data architectures.

Vinayaka Gangadhar

Vinayaka Gangadhar

Vinayaka is an Analytics Specialist at Amazon Web Services (AWS), where he helps customers build and troubleshoot scalable data platforms and derive meaningful insights through AWS analytics services, with deep expertise in Amazon Redshift and Amazon OpenSearch. When not solving complex analytics challenges, he enjoys exploring new technologies and spending quality time with his family.

Kalyan Janaki

Kalyan Janaki

Kalyan is Senior Big Data & Analytics Specialist with Amazon Web Services. He helps customers architect and build highly scalable, performant, and secure cloud-based solutions on AWS.

Amazon MSK Service 101: How many partitions does an Amazon MSK topic need?

Post Syndicated from Yashika Jain original https://aws.amazon.com/blogs/big-data/amazon-msk-service-101-how-many-partitions-does-an-amazon-msk-topic-need/

Customers new to Amazon Managed Streaming for Apache Kafka (Amazon MSK) often ask how many partitions their topics need. Choosing the right partition count is one of the most impactful architectural decisions you make, because it directly affects throughput, scalability, and operational complexity.

In Apache Kafka, a topic is the fundamental unit for categorizing data streams, but to achieve high scalability and performance, Kafka divides topics into smaller, independent units called partitions.

In this post, we provide practical guidance for determining the ideal partition count for your use case.

Understanding Kafka partitions

In
Apache Kafka, a partition is the unit of storage and parallelism. Each partition is an ordered, immutable log that can store records as they are produced to a topic. When you create a topic, Kafka distributes its partitions across the brokers in the cluster. Partitions allow Kafka to scale in three key ways:
  • Parallelism – Within a consumer group, each partition can be read by only one consumer at a time. Each partition maps to a dedicated log file in storage on the broker, and Kafka manages these logs through separate processing threads. This architecture allows more partitions to support more consumers processing data in parallel, with each partition’s log being independently managed for read and write operations.
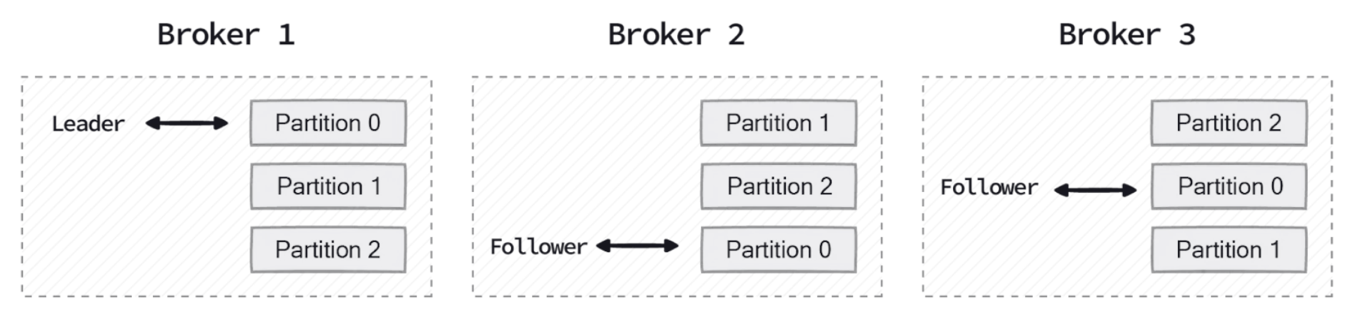
The following diagram shows how Kafka distributes partition replicas across a three-broker cluster, with each broker serving as a leader for some partitions and a follower for others.
Partitions 0, 1, and 2 replicated across three brokers, each a leader for some partitions and a follower for others

Figure 1: Partition replicas distributed across a three-broker cluster

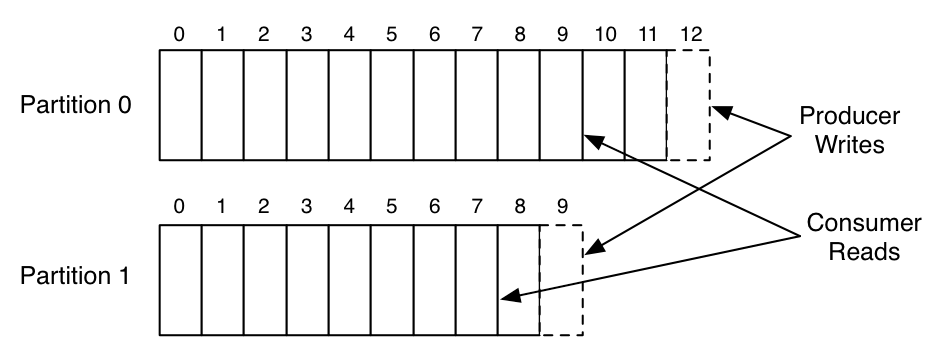
The following diagram illustrates how producers append new records to the end of a partition log, while consumers read sequentially from their current offset position.

Producers append records to the tail of partition logs while consumers read sequentially from their offset position

Figure 2: Producer writes and consumer offset positions in two partition logs

  • Throughput – Producers and consumers can read and write data in parallel across partitions, increasing overall throughput.
  • Scalability – Partitions allow Kafka to spread data and load across multiple brokers instead of concentrating it on a single node.

However, increasing partitions comes with trade-offs. Each partition adds metadata overhead, consumes memory, and requires file handles on the broker. While more partitions improve throughput and parallelism, they also increase the operational burden on the cluster. Too many partitions can lead to longer leader election times during broker failures, increased end-to-end latency, and higher memory consumption for both producers and consumers managing connections to multiple partitions.

Trade-offs when choosing partition count

Choosing a partition count is a balancing act between parallelism and resource utilization.

Benefits of more partitions

Using more partitions can significantly improve throughput by allowing Kafka to distribute read and write traffic across more brokers. This is particularly useful for high-volume ingestion pipelines and real-time analytics workloads. More partitions also allow consumer groups to scale horizontally, because the maximum number of active consumers in a group is limited by the number of partitions. In addition, choosing a partition count that is evenly divisible by the number of brokers helps provide balanced leadership and replica distribution, reducing the risk of uneven load.

Operational costs of more partitions

However, higher partition counts also come with costs. When a broker fails or undergoes maintenance, Kafka must perform recovery operations for each affected partition. During recovery, Kafka elects new leaders for partitions that were hosted on the unavailable broker and replicates data from the remaining in-sync replicas to newly assigned brokers. This process involves copying partition data across the network to restore the replication factor, which can be resource intensive. As the number of partitions increases, these recovery operations take longer because each partition requires its own leader election and data replication cycle.

You might encounter clusters with very high partition counts that experience extended recovery times during rolling upgrades, even when overall traffic volumes are modest. Amazon MSK Express brokers address this challenge by recovering 90x faster and providing 180x faster elasticity when scaling out clusters. This significantly reduces the operational impact of high partition counts during maintenance windows and failure scenarios.

Infrastructure cost implications

Beyond operational complexity, more partitions can directly increase infrastructure costs. Amazon MSK publishes partition-per-broker limits that vary by instance type. When the total partition count (including replicas) exceeds what the current broker fleet can support, you must add brokers to stay within recommended limits, even if throughput alone does not warrant the additional capacity.

Amazon MSK partition-per-broker guidelines

Amazon MSK publishes recommended partition-per-broker guidelines to help you operate clusters reliably. These values are strict limits. Exceeding them can lead to operational challenges, particularly during broker replacement or rolling upgrades, and can block cluster operations such as configuration updates or scaling down.

Express brokers support up to 5x more partitions per broker compared to Standard brokers. For example, the largest Standard broker (kafka.m7g.16xlarge) supports a recommended maximum of 4,000 partitions per broker. The equivalent Express broker (express.m7g.16xlarge) supports up to 20,000 recommended partitions per broker. This higher partition density means partition-bound workloads can be hosted on fewer brokers, improving price-performance by up to 50% for such workloads.

We recommend setting Amazon CloudWatch alarms on PartitionCount per-broker metrics to proactively monitor your partition distribution. When an alarm triggers, evaluate your partition strategy and consider rebalancing partitions across brokers, consolidating topics, or scaling out your cluster to stay within recommended limits. For detailed guidance, see Right-size your cluster: Number of partitions per Standard broker and Express broker partition quota.

Practical guidance for choosing a partition count

There is no single formula that works for every Kafka workload. In practice, you typically combine several considerations when sizing partitions.

  • Start with throughput requirements – The first step is to determine your per-partition throughput capacity, which then informs how many partitions you need.

For Express brokers, use the per-broker throughput capacity as the primary means for sizing your cluster. Express brokers feature a fully managed storage layer, so you do not need to separately account for storage I/O constraints. The published per-broker limits represent the effective capacity available to your workload.

For Standard brokers, the achievable throughput depends on additional factors beyond the broker instance size. These factors include provisioned EBS storage throughput, the number of consumer groups reading from the broker, and how much data is served from memory versus disk. Storage I/O is consumed when producers write, when data replicates between brokers, and when consumers read data that is not in memory. For this reason, validate the effective per-partition throughput for Standard brokers through load testing in your environment.

Once you know your per-partition throughput, calculate the required number of partitions: Number of partitions = Peak throughput of the topic ÷ Throughput per partition

For example, if a topic must handle 40 MB/sec at peak and your testing shows each partition can sustain 5 MB/sec, you would need: 40 ÷ 5 = 8 partitions. Always validate these assumptions with load testing, as actual throughput varies based on your workload characteristics. For initial sizing estimates, refer to the Amazon MSK Sizing and Pricing worksheet and the Amazon MSK Best Practices documentation.

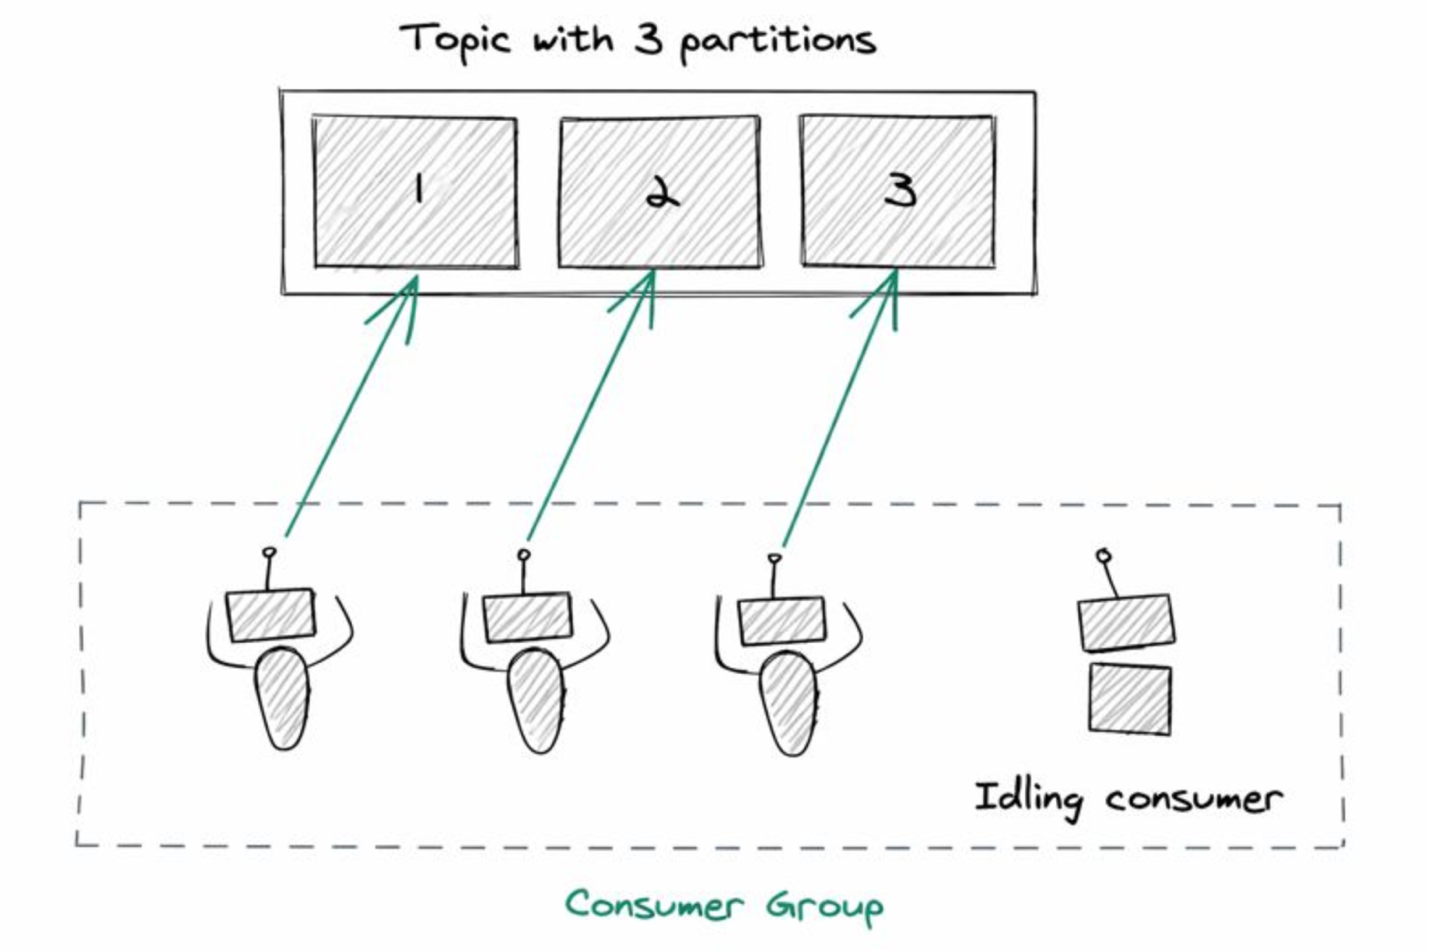
  • Consider your consumer parallelism needs – If you know the number of consumers required during peak processing times, use that as your partition count. We don’t recommend having more active consumers in a consumer group than partitions. For example, if you have 5 partitions, only 5 consumers can actively process data. Additional consumers remain idle. These idle consumers still maintain active TCP connections to the brokers, sending frequent heartbeats and group coordination requests. This might result in unnecessary overhead on broker resources and contribute to high CPU usage despite low egress traffic.
Consumer group with more consumers than partitions, leaving the extra consumers idle

Figure 3: Idle consumers when a consumer group has more consumers than partitions

  • Producer throughput and partition keys – When sizing partitions, consider producer-side throughput in addition to consumer parallelism. If producers generate data faster than a single partition can handle, additional partitions can help distribute write traffic across brokers. Partition keys also play a critical role. Poorly distributed or low-cardinality keys can create hot partitions and limit throughput. In such cases, increasing the number of partitions alone does not improve throughput unless records are evenly distributed.
  • Plan for even distribution and future growth – Kafka works best when partitions can be spread evenly across brokers. Instead of focusing on specific numbers, aim for partition counts that divide reasonably well across your expected broker count. This reduces reassignment churn when brokers are added or replaced. But avoid excessive over-partitioning. It’s reasonable to leave some headroom for future growth. However, creating thousands of partitions “just in case” often causes more harm than good. Increasing partitions later is supported, but it can affect ordering guarantees and may require consumer changes. Start with a conservative number, monitor real traffic patterns, and scale gradually.

From an operational perspective, Amazon MSK provides recommended partition-per-broker guidelines based on broker instance type. Exceeding these guidelines increases operational risk and can block cluster operations such as version upgrades, scaling, or configuration changes. Large partition counts can also increase consumer group rebalance duration, temporarily pausing message processing and increasing end-to-end latency.

Keep in mind that partitioning improves scalability, but it does not address application-level bottlenecks such as slow consumers, inefficient processing logic, or downstream system constraints.

Conclusion

Determining the right number of partitions for an Amazon MSK topic is a foundational design decision. It affects throughput, scalability, failure recovery, and day-to-day operability of your Kafka cluster. Start by understanding your throughput and consumer parallelism needs, respect Amazon MSK partition-per-broker guidelines, avoid excessive over-partitioning, and validate assumptions through load testing. Most importantly, there is no universal “correct” number, only a number that fits your workload, operational goals, and cost.

For more information, see the Amazon MSK Developer Guide and Recommended best practices for Amazon MSK.


About the authors

Yashika Jain

Yashika Jain

Yashika is a Senior Cloud Analytics Engineer at AWS, specializing in real-time analytics and event-driven architectures. She is committed to helping customers by providing deep technical guidance, driving best practices across real-time data platforms and solving complex issues related to their streaming data architectures.

Ali Alemi

Ali Alemi

Ali is a Principal Streaming Solutions Architect at AWS. Ali advises AWS customers with architectural best practices and helps them design real-time analytics data systems which are reliable, secure, efficient, and cost-effective. Prior to joining AWS, Ali supported several public sector customers and AWS consulting partners in their application modernization journey and migration to the Cloud.

Set up production-ready monitoring for Amazon MSK using CloudWatch alarms

Post Syndicated from Yashika Jain original https://aws.amazon.com/blogs/big-data/set-up-production-ready-monitoring-for-amazon-msk-using-cloudwatch-alarms/

Organizations running Apache Kafka as their streaming platform need comprehensive monitoring to maintain reliable operations. Without proper visibility into broker health, resource utilization, and data flow metrics, teams risk service disruptions, data loss, and degraded performance that can impact critical business operations. Effective monitoring and alerting are essential to detect anomalies early, from high system load to connectivity issues, enabling teams to take preventive action before problems affect production workloads.

Amazon Managed Streaming for Apache Kafka (Amazon MSK) addresses these monitoring challenges by publishing detailed metrics to Amazon CloudWatch. The service emits metrics at 1-minute intervals for provisioned (Standard) clusters, with flexible monitoring levels (DEFAULT, PER_BROKER, PER_TOPIC_PER_BROKER, or PER_TOPIC_PER_PARTITION) to control granularity and cost. At the DEFAULT level (free), cluster-level metrics are available; higher levels (paid) expose broker-level, per-topic and per-partition metrics.

In this post, I show you how to implement effective monitoring for your MSK clusters using Amazon CloudWatch. You’ll learn how to track critical metrics like broker health, resource utilization, and consumer lag, and set up automated alerts to prevent operational issues. By following these practices, you can work to improve streaming operations reliability, optimize resource usage, and support high availability for your mission-critical applications.

Key metrics to monitor

This article groups important Amazon MSK metrics into logical categories. For each, we highlight key metrics and what they indicate:

  1. Broker Health and Cluster Availability:
    • ActiveControllerCount is a cluster-level metric where each broker reports whether it’s the active controller (1) or not (0). In a healthy cluster, exactly one broker serves as the active controller at any time. When viewing this metric with the average statistic, the value equals 1 divided by the number of brokers. For example, a 3-broker cluster shows 0.33 (1/3). Set CloudWatch alarm thresholds accordingly—for 6 brokers, alert if average falls below 0.166(1/6). When using the sum statistic, the value should always be 1, indicating one active controller regardless of cluster size. If the sum differs from 1, a controller election is in progress—typically during maintenance activities, configuration changes, or rolling restarts.
      Note: For a KRaft-based clusters, the ActiveControllerCount is only exposed on dedicated controller endpoints so the sample count is 3 and only controller will report value of 1. Thus, the average is always 0.33 no matter how many brokers there are in the cluster. To monitor the broker health for Kraft-based clusters, check LeaderCount metric. If a broker is not emitting any metric, then it’s a good indication that broker might be unhealthy.
    • OfflinePartitionsCount (cluster): Number of partitions with no active leader. Non-zero values mean data is temporarily unavailable or unwritable. Trigger alerts if it rises above 0.
    • UnderReplicatedPartitions (per broker): Number of partitions where not all replicas are caught up. This should stay at 0 under normal conditions. Spikes indicate traffic exceeds capacity or replication lag; sustained values often mean a configuration/ACL issue. Refer to Troubleshoot your Amazon MSK cluster
    • UnderMinIsrPartitionCount (per broker): Partitions below the minimum in-sync replica (ISR) count. A non-zero value means potential data loss risk if brokers fail. Monitor to ensure replication is healthy. Refer to Custom configurations
    • GlobalPartitionCount (cluster): Total number of partitions across all topics (leaders only). Useful for capacity planning and sanity checks.
    • PartitionCount (per broker): Number of partitions (including replicas) hosted by a broker. Sudden changes may indicate re-balances. (Excess partitions per broker can degrade performance).
  2. Resource Utilization:
    • CPU: Total broker CPU utilization is defined as CpuUser + CpuSystem. Best practice is to keep average CPU utilization under 60% . Set alarms on the sum of user+system to detect overload.
    • CPUCreditBalance / CPUCreditUsage (per broker): For burstable instance types(T3), tracks earned/spent CPU credits. A declining credit balance or high credit usage warns that the instance may be CPU-starved.
    • Memory: MemoryUsed, MemoryFree (per broker) show RAM usage. Critically, HeapMemoryAfterGC (per broker) reports JVM heap usage (%) after garbage collection. AWS recommends alerting if HeapMemoryAfterGC exceeds 60%, to avoid out-of-memory issues.
    • Disk: Kafka brokers use attached EBS storage for topic data. Monitor KafkaDataLogsDiskUsed (per broker) – percentage of disk used by message logs. Best practice: alarm when data log usage exceeds 85%. Also track RootDiskUsed: the percentage of the root disk used by the broker.
    • EBS I/O: Volume metrics (per broker) such as VolumeQueueLength, VolumeReadOps, VolumeWriteOps, VolumeReadBytes, VolumeWriteBytes indicate I/O latency and throughput. Rising queue lengths or latency (such as VolumeTotalReadTime) suggest disk contention.
    • Network: Basic network stats per broker include NetworkRxPackets, NetworkTxPackets, and errors/drop counts (NetworkRxErrors, NetworkTxErrors, NetworkRxDropped, NetworkTxDropped). Unexpected errors or drops can indicate network issues.
  3. Topic and Partition Activity:
    • Throughput: BytesInPerSec and BytesOutPerSec measure inbound/outbound data rates per broker or per topic. Sustained drops can signal lost producers/consumers; spikes may require scaling.
    • Replication Traffic: ReplicationBytesInPerSec/ReplicationBytesOutPerSec (per topic) show inter-broker replication volume.
    • Consumer Lag: Consumer lag metrics quantify the difference between the latest data written to your topics and the data read by your applications. Amazon MSK provides the following consumer-lag metrics, which you can get through Amazon CloudWatch or through open monitoring with Prometheus: EstimatedMaxTimeLag, EstimatedTimeLag, MaxOffsetLag, OffsetLag, and SumOffsetLag. For information about these metrics, see Amazon MSK metrics for monitoring Standard brokers with CloudWatch.
  4. Client Connections :
    • ConnectionCount (per broker): Total active connections (clients + inter-broker). Sudden drops or sustained high counts (hitting limits) merit attention.
    • ClientConnectionCount (per broker, with auth filter): Active authenticated client connections.
    • ConnectionCreationRate / ConnectionCloseRate (per broker): New or closed connections per second. Spikes in connection churn may indicate client issues.
    • Authentication: IAMNumberOfConnectionRequests and IAMTooManyConnections (per broker) show IAM auth request rates and throttle breaches (limit of 100 simultaneous connections).
  5. Network Bandwidth Metrics:
    • TrafficShaping > 0 (any throttling) metric serves as your primary warning signal. When this value exceeds zero, your MSK cluster is experiencing network throttling at the EC2 layer, with packets being dropped or queued due to exceeded allocations. This throttling manifests as reduced throughput, increased latency, and potential network errors that impact both producer and consumer performance. TrafficShaping issues stem from two possible bandwidth limitations: BwInAllowanceExceeded & BwOutAllowanceExceeded :
    • BwInAllowanceExceeded tracks when inbound aggregate bandwidth surpasses broker maximums.
    • BwOutAllowanceExceeded monitors when outbound aggregate bandwidth exceeds limits.
      Both BwInAllowanceExceeded and BwOutAllowanceExceeded metrics directly contribute to overall network throttling events.
  6. Other Operational Metrics:
    • Thread Pools: RequestHandlerAvgIdlePercent, NetworkProcessorAvgIdlePercent (per broker) show how busy Kafka’s internal thread pools are. Consistently low idle (%) can indicate bottlenecks.
    • ZooKeeper: For ZooKeeper-based MSK clusters, ZooKeeperRequestLatencyMsMean and ZooKeeperSessionState reflect ZK performance (for older Kafka versions that use Zookeeper). For ZooKeeperSessionState, anything other than 1 for 5-10 mins should be alarming as there can be chances broker has an issue or zookeeper is not able to connect to brokers due to some intermittent network issue.
    • Tiered Storage: For clusters with tiered storage enabled, Amazon MSK provides metrics like RemoteFetchBytesPerSec, RemoteCopyBytesPerSec, RemoteLogSizeBytes, and related error/queue metrics. These track offloading to remote storage.
    • Intelligent rebalancing metrics: For MSK Provisioned clusters using Express brokers, Amazon MSK provides two key metrics to monitor rebalancing operations: RebalanceInProgress and UnderProvisioned metrics. See Monitor Intelligent rebalancing metrics

By grouping metrics into these categories, you can build dashboards and alerts that comprehensively cover Amazon MSK health and performance. Amazon CloudWatch also provides automatic dashboards for Amazon MSK.

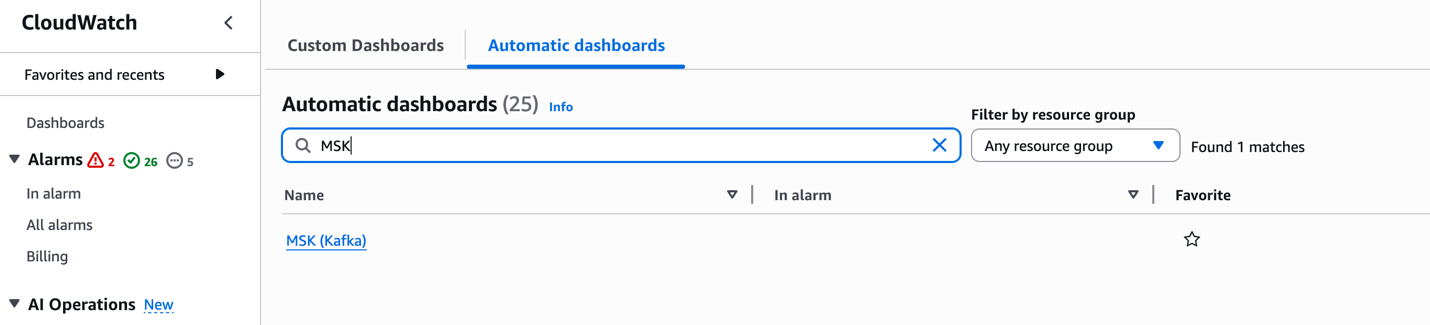
Let’s take a quick look on how to access CloudWatch automatic dashboard. In the AWS Console, go to the CloudWatch service. When in the CloudWatch console, select Dashboards. Open the Automatic dashboard tab and search for MSK in the Filter Bar.

These dashboards offer per-configured visualizations of key metrics, enabling quick insights into the health and performance of your MSK clusters.

Recommended CloudWatch alarms

Setting alarms on key metrics helps catch issues early. Detecting issues early is crucial in streaming applications where every second counts. A single failing broker can trigger a chain reaction – halting data ingestion, backing up upstream systems, and breaking downstream applications. This can quickly escalate from delayed order processing to lost revenue. Proactive monitoring helps catch and fix problems before they impact your business operations. Based on AWS best practices and experience, consider alarms such as:

Metric (Dimension) Alarm Condition Rationale
ActiveControllerCount (cluster) ≠ 1 (count) Only one active controller should exist. Deviation implies cluster instability.
CPU Utilization (Sum(CPUUser+CPUSystem), per broker) > 60% (average) for 5+ mins Helps maintain headroom for broker load and maintenance. High CPU may slow processing as outlined in the MSK best practices documentation
HeapMemoryAfterGC (broker) > 60% (percentage) Indicates Kafka heap is filling up. Helps prevent OOM by alerting early.
KafkaDataLogsDiskUsed (broker) ≥ 85% (percent) Warns that disk is nearly full. Helps prevent data loss by providing time for scaling or cleanup.
OfflinePartitionsCount (cluster) > 0 (count) Any offline partition means unavailable data. Immediate investigation needed.
UnderReplicatedPartitions (broker) > 0 (count) No replicas lagging under healthy conditions. Spikes or sustained lag can indicate overload or ACL misconfiguration.
UnderMinIsrPartitionCount (broker) > 0 (count) There must be topics with partitions that have either less in-sync replicas than the min.insync.replicas setting or with RF=MinISR. To find these topics whose partitions are under replicated, use command:
<path-to-your-kafka-installation>/bin/kafka-topics.sh –bootstrap-server <bootstrap-server:port> —command-config client.properties –describe –under-min-isr-partitions
ConnectionCount (broker) Sudden drop (e.g. < 90% of baseline) or spike above high threshold Detect client connectivity issues or connection floods. Unexpected drops may mean a broker is unreachable. Refer to Amazon MSK Standard broker quota
CPUCreditBalance (for T3 broker) < some low threshold (e.g. 10 credits) For burstable instances, alerts when credits are nearly exhausted, which degrades performance.
VolumeQueueLength (broker) > 0 (sustained) or rising Indicates I/O operations are queuing, possible disk bottleneck.
NetworkRxErrors/TxErrors (broker) > 0 (count) Any network errors can cause packet loss or disconnections.
IAMTooManyConnections (broker) > 0 (count) Exceeding IAM connection limit (100) blocks new connections.
Consumer Lag (MaxOffsetLag or SumOffsetLag) (per consumer-group/topic) > threshold (depends on SLAs, e.g. growing beyond expected) Alerts on slow consumers so you can scale consumers or investigate backlogs.
TrafficShaping > 0 (any throttling) This is an indication that brokers are exceeding their allocated network bandwidth.

These are illustrative thresholds; adjust them for your workload and SLAs. The remaining metrics listed in the CloudWatch metrics for Standard and Express brokers documentation are susceptible to downstream impact from anomalies in the primary metrics above. It is recommended to enable CloudWatch alarms on a single test cluster first to validate thresholds before extending coverage across your MSK fleet.

Conclusion

In this post, we covered the important CloudWatch metrics and alarms for monitoring Amazon MSK clusters effectively. By implementing these recommended alarms, you can proactively detect and respond to potential issues before they impact your Kafka workloads. To learn more about Amazon MSK monitoring, refer to the Amazon MSK Monitoring Best Practices documentation or explore our Amazon MSK Workshops hands-on experience.


About the authors

Yashika Jain

Yashika Jain

Yashika is a Senior Cloud Analytics Engineer at AWS, specializing in real-time analytics and event-driven architectures. She is committed to helping customers by providing deep technical guidance, driving best practices across real-time data platforms and solving complex issues related to their streaming data architectures.