Tag Archives: Amazon Managed Streaming for Apache Kafka (Amazon MSK)

Migrate an OAuth 2.0 authenticated Apache Kafka cluster to Amazon MSK with MSK Replicator

Post Syndicated from Subham Rakshit original https://aws.amazon.com/blogs/big-data/migrate-an-oauth-2-0-authenticated-apache-kafka-cluster-to-amazon-msk-with-msk-replicator/

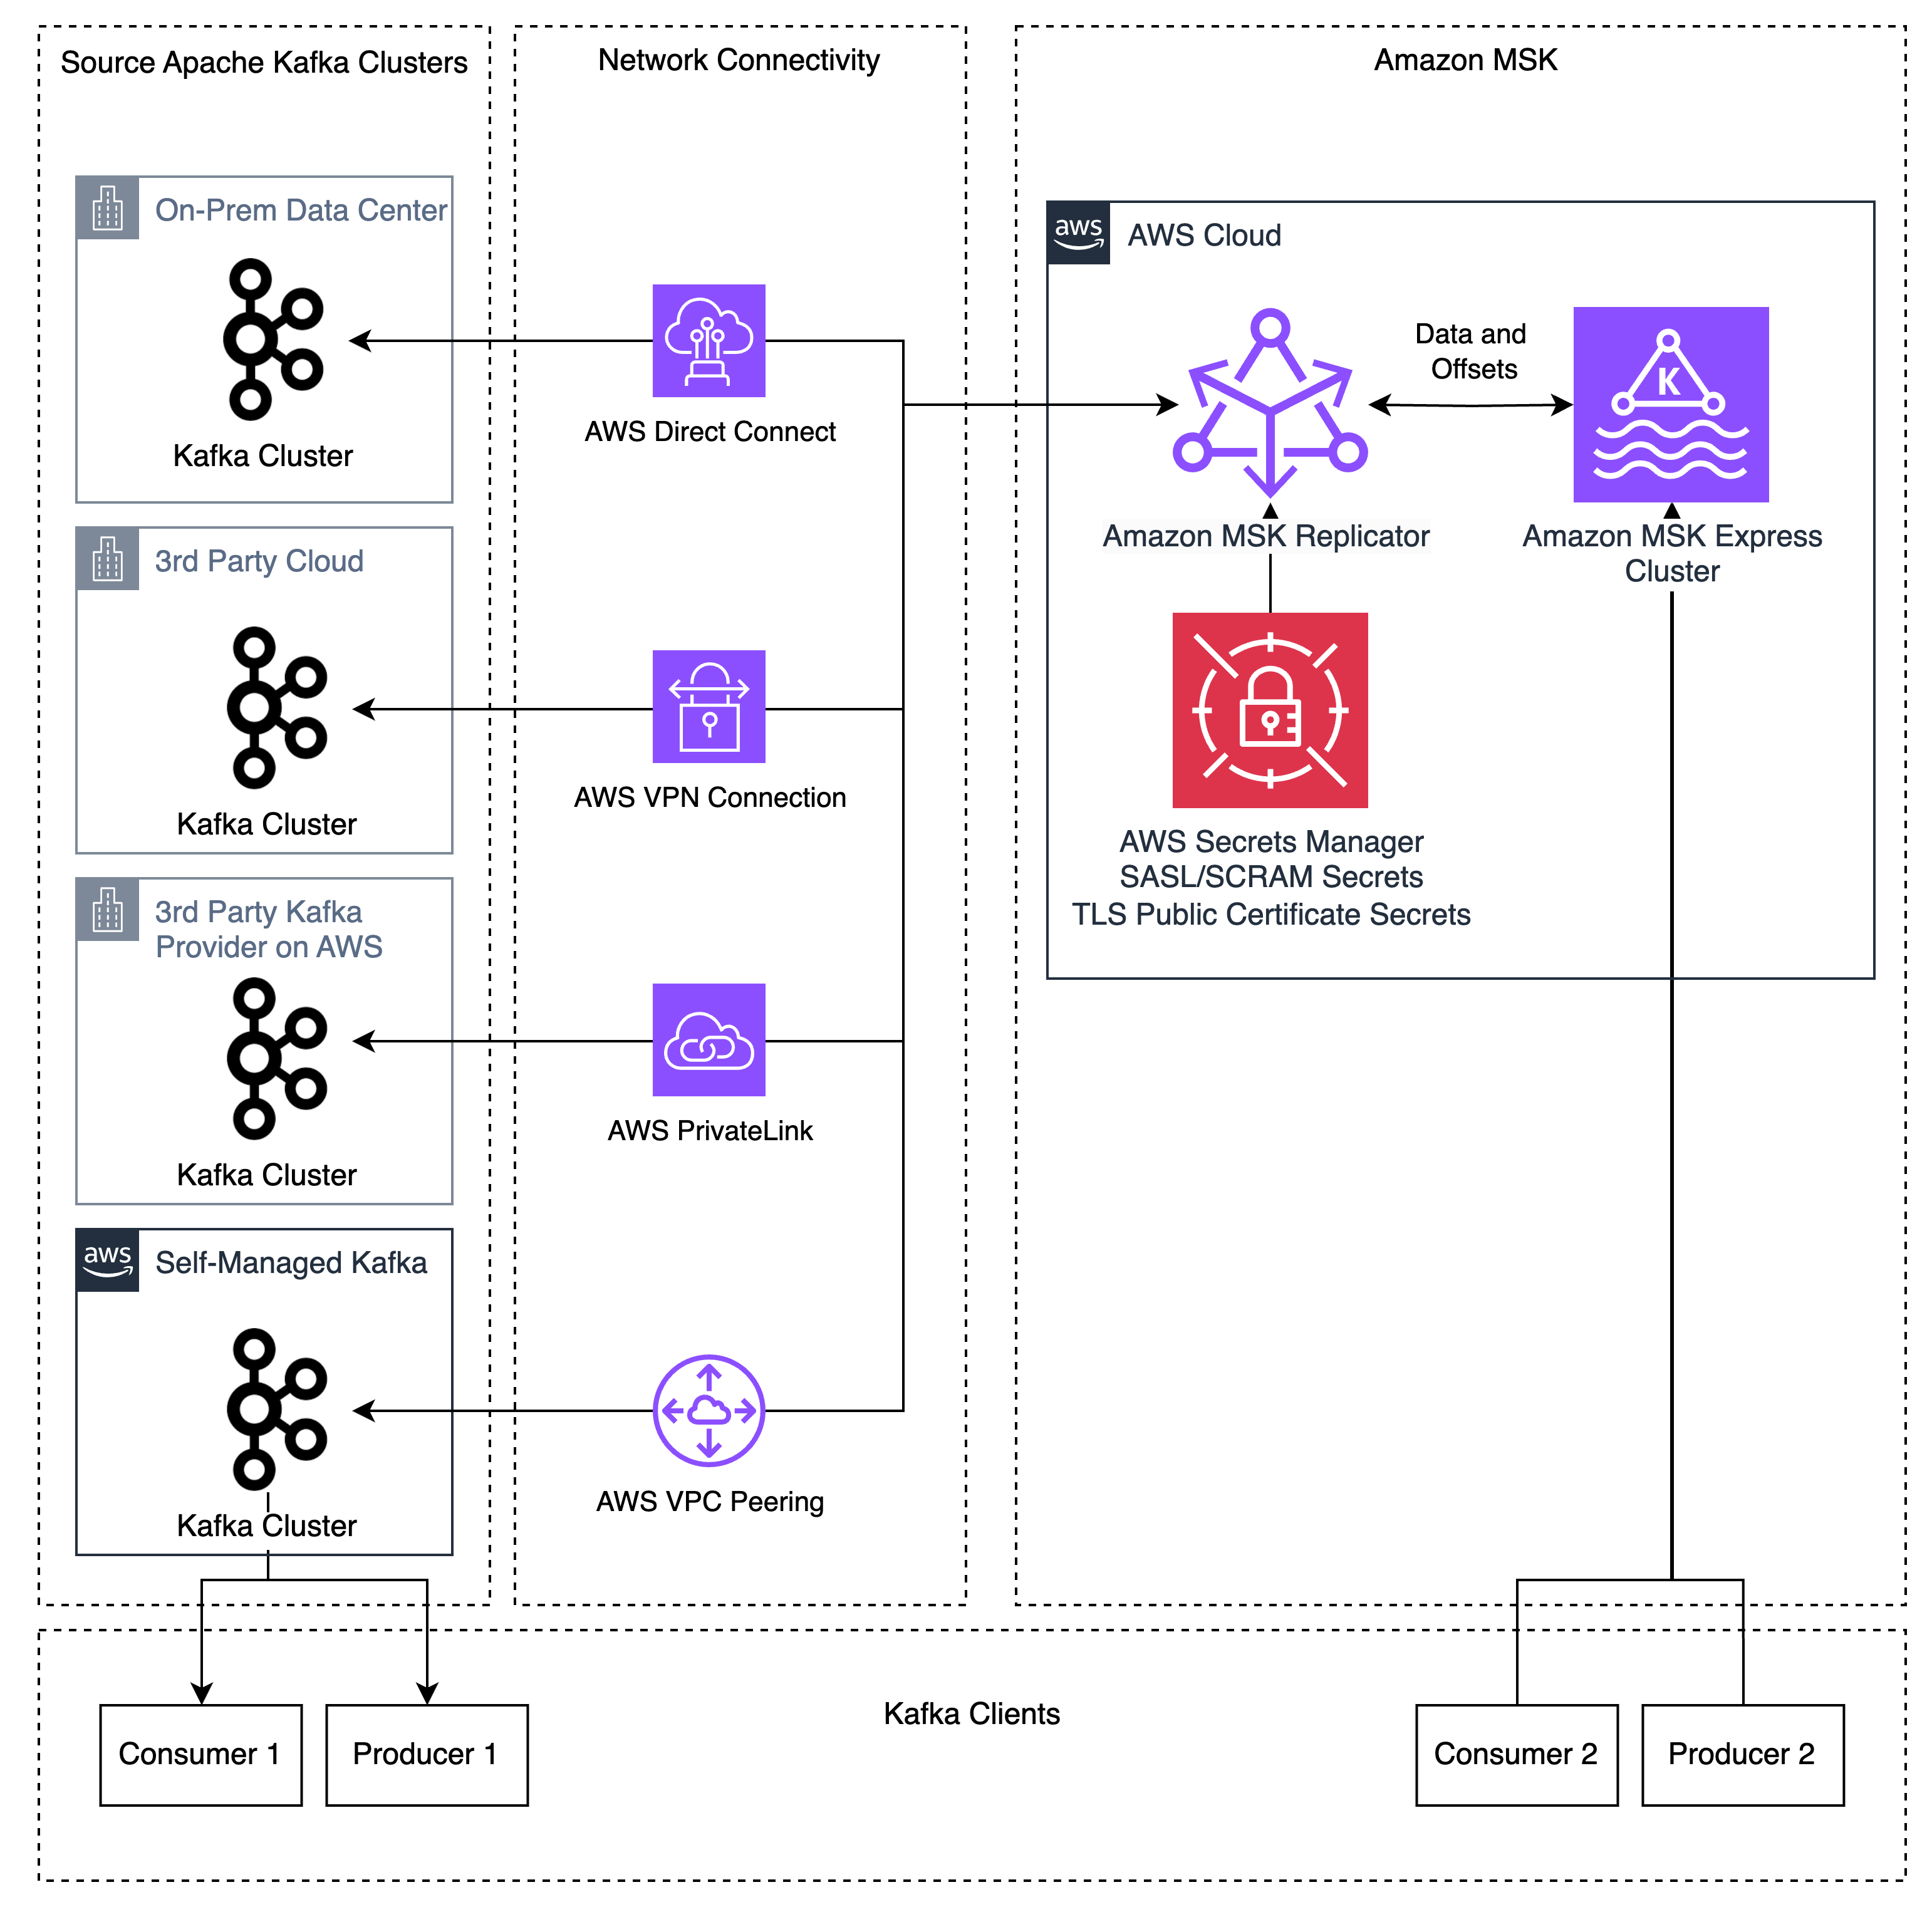
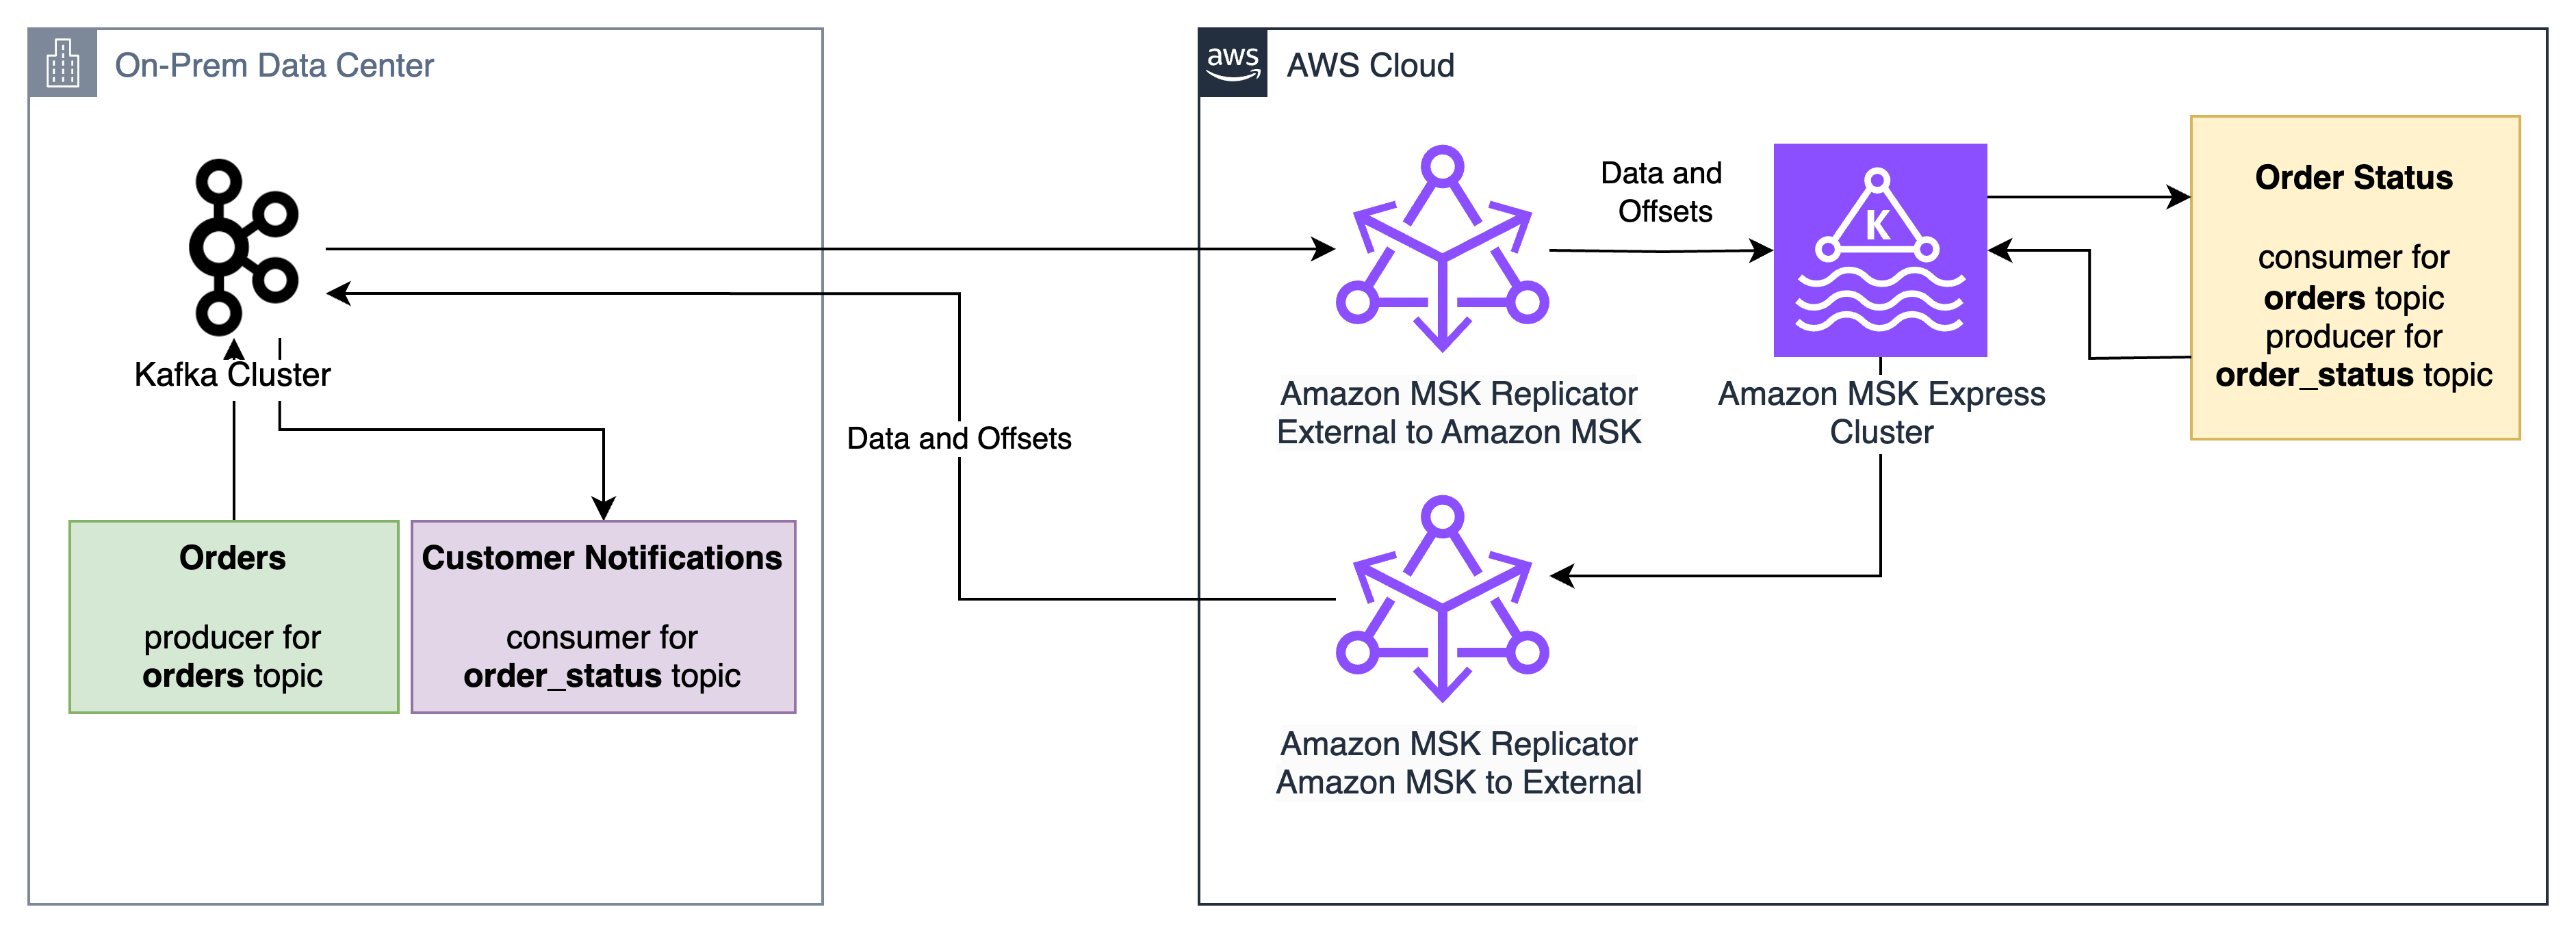
In an earlier post, we walked through how Amazon Managed Streaming for Apache Kafka (Amazon MSK) Replicator migrates external and self-managed Apache Kafka clusters to Amazon MSK. It replicates your topics and their configurations, keeps topic and consumer-group names intact, and synchronizes consumer-group offsets, so your producers and consumers can cut over on their own schedule instead of all at once. MSK Replicator now supports OAuth 2.0 (SASL/OAUTHBEARER) authentication to the external cluster, and that is what this post covers.

If your external Kafka cluster authenticates clients with OAuth, MSK Replicator can connect to it, but “OAuth” isn’t a single thing you switch on. It’s a family of grant types, and each one comes with its own trust model, its own set of inputs you need to supply, and its own configuration on both the Replicator side and your identity provider (IdP) side.

In this post, we walk you through the grant types one by one, show you how to configure Replicator for each, call out the network and TLS prerequisites that are commonly missed, and finish with how to handle IdPs that sit behind an additional identity layer. This mechanism works with any OAuth 2.0 (OIDC) identity provider, including Keycloak, Okta, Microsoft Entra ID, PingFederate, and Auth0. OAuth here governs only how Replicator authenticates to your external cluster, so the target can be either Amazon MSK Standard or Express brokers, which always use IAM.

How OAuth authentication works

Before you configure Replicator, it helps to be precise about how the OAuth Kafka handshake works.

The components

  • The Identity Provider (IdP) – Issues access tokens and publishes the public keys. Brokers use these keys to verify the tokens. Examples: Keycloak, Okta, Microsoft Entra ID, PingFederate, Auth0, or a custom OIDC server.
  • The client – In our case, MSK Replicator, acting as a Kafka consumer/producer against your external cluster.
  • The resource server – Your self-managed Kafka broker, which must decide whether to admit a connection.
  • The access token – A JWT (JSON Web Token): a base64url-encoded, three-part string header.payload.signature that the IdP cryptographically signs.

The SASL/OAUTHBEARER handshake, step by step

The following sequence diagram shows the full exchange, from Replicator requesting a token to the broker accepting the connection:
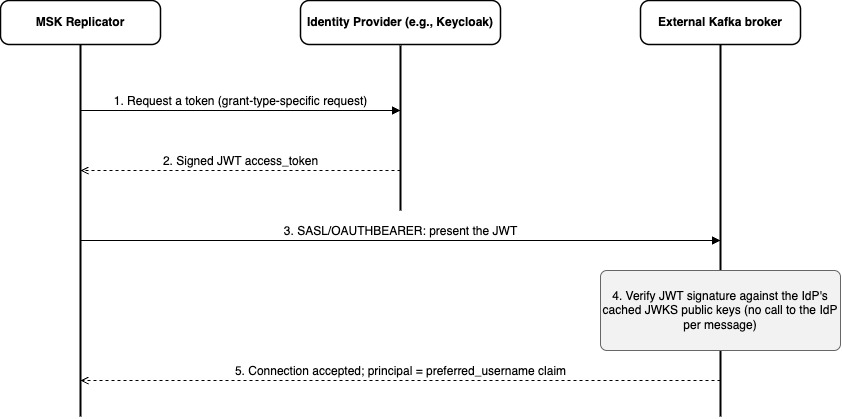
Sequence diagram of the SASL/OAUTHBEARER handshake: Replicator requests a token from the IdP, receives a signed JWT, presents it to the Kafka broker, and the broker verifies the JWT against cached JWKS keys before accepting the connection.

Figure 1: The SASL/OAUTHBEARER handshake. Replicator gets a signed JWT from the IdP and presents it to the broker, which verifies it against cached JWKS keys before accepting the connection.

Walking through it:

  1. Request a token – Replicator asks the IdP for an access token. The exact request depends on the grant type (covered in the next section).
  2. Receive a signed JWT – The IdP returns a signed JWT access token.
  3. Present the token – Replicator opens a SASL/OAUTHBEARER connection to the external Kafka brokers and presents the JWT.
  4. Verify locally – The broker verifies the JWT signature against the IdP’s cached JWKS public keys, without calling the IdP per message.
  5. Connection accepted – The broker admits the connection and derives the Kafka principal from the preferred_username claim.

Step 4 is worth dwelling on: the broker validates the token locally. It fetches the IdP’s JWKS (JSON Web Key Set, the public half of the IdP’s signing keys, RFC 7517) from an endpoint like https://idp.example.com/realms/kafka/protocol/openid-connect/certs and caches it, refreshing on a configurable interval (and re-fetching if it sees a key ID it doesn’t recognize). Incoming JWT signatures are then verified against those cached keys. The IdP is not in the hot path of message traffic. It is contacted only to (a) issue tokens to clients, and (b) serve its public keys for the periodic JWKS refresh.

What the Kafka broker checks

When Replicator presents a JWT, the broker validates:

  • Signature – Proves the IdP issued the token and no one tampered with it (verified against JWKS).
  • iss (issuer) – Must match the broker’s configured oauth.valid.issuer.uri, byte-for-byte, including scheme, host, port, and path. A mismatch is a common configuration error.
  • exp (expiry) – Expired tokens are rejected. Strimzi’s client callback handler proactively refreshes before expiry, so you shouldn’t see mid-stream failures.
  • The principal claim – Typically preferred_username. The broker uses this as the Kafka principal in ACLs (for example, User:service-account-msk-replicator). This matters: the identity Replicator authenticates as on the external cluster must have ACLs that you configure to grant it the read/describe permissions it needs.

Mapping your IdP to a Replicator grant type

A grant type is the protocol by which the client proves its identity to the IdP and obtains a token. This is the front half of the preceding handshake (steps 1 and 2). MSK Replicator supports three of them. You already know how your Kafka clients authenticate to your IdP today, so start from that.

Which grant to use?

Find the row that matches how your clients get tokens today:

How your Kafka clients get tokens from the IdP today Grant type Long-lived secret? What you trust/register on the IdP
A client_id / client_secret (confidential client) CLIENT_CREDENTIALS Yes (stored on AWS Secrets Manager) Nothing new: reuse the existing client, or create one for Replicator
You want secretless, and your IdP can trust an external token issuer IAM_JWT_BEARER No AWS STS as an external token (OIDC) issuer. Trust its JWKS
You want secretless, and your IdP models workloads as signed-JWT clients CLIENT_CREDENTIALS_ASSERTION No AWS STS as the client’s signing authority (private_key_jwt). Trust its JWKS

The simplest mapping is like-for-like: if your clients use a client_id/client_secret, point Replicator at the same client with CLIENT_CREDENTIALS. If you’d rather not give Replicator a long-lived secret, the two secretless grants let it authenticate with its AWS identity instead. Choose between them based on how your IdP prefers to trust an external party.

The rest of this section explains why the three grants differ, using an analogy. If your row is clear and you only want the configuration, skip ahead to Configuring and creating the replicator.

A scenario: checking in at a secure office building

A visitor needs to get into a secure office building. They can’t walk straight in. First they stop at the reception desk to prove who they are and collect a temporary access pass. Only then can they use that pass at the building’s turnstile to get inside. In OAuth terms: the building is your external Kafka cluster, the reception desk is the IdP, the temporary access pass is the access token (JWT), and the visitor is MSK Replicator. Presenting the pass at the turnstile is the SASL/OAUTHBEARER step, and it works the same way for every grant type. What differs is how the visitor proves who they are at the reception desk before it prints a pass.

Scenario 1: CLIENT_CREDENTIALS (the shared PIN)
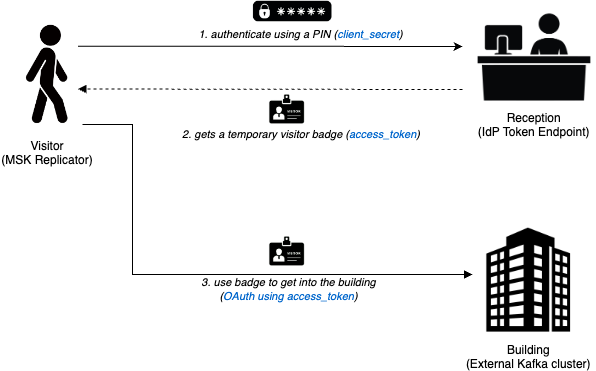
CLIENT_CREDENTIALS scenario shown as a visitor entering a building: the visitor authenticates at reception with a PIN (the client secret), receives a temporary badge (the access token), and uses it to enter the building (the Kafka cluster).

Figure 2: CLIENT_CREDENTIALS. The visitor authenticates at reception with a PIN (the client_secret), gets a temporary badge (the access token), and uses it to enter the building (the Kafka cluster).

At the reception desk the visitor keys in a PIN the desk already have on file (the client_secret), collects a temporary access pass in return (the access token), and uses that pass to get into the building. Both sides hold the same secret. In practice (RFC 6749 §4.4), Replicator authenticates to the IdP with a client_id/client_secret stored on AWS Secrets Manager, receives the access token, and presents it to the external Kafka brokers over SASL/OAUTHBEARER. Use it when your IdP already issues client secrets for machine clients. This is usually a like-for-like move that reuses the client your existing producers and consumers use, or a new one created for Replicator.

Scenario 2: IAM_JWT_BEARER (the badge is the request)
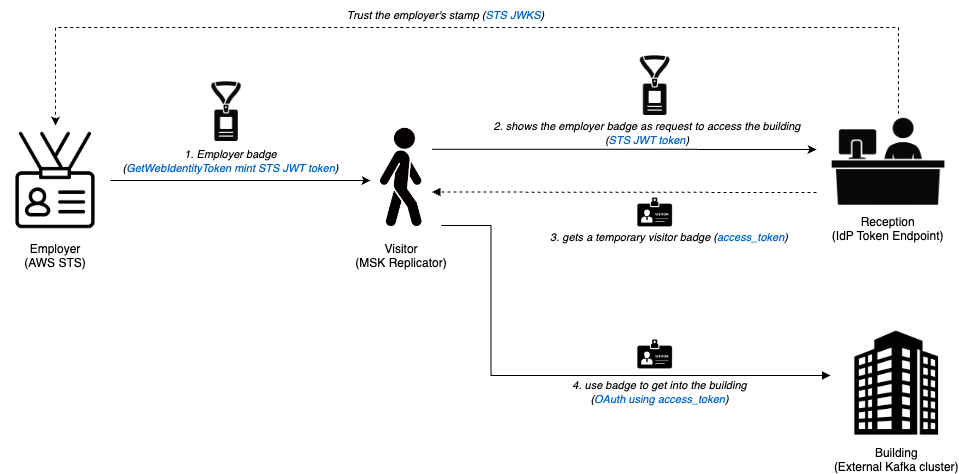
IAM_JWT_BEARER scenario: the visitor presents an employer-signed badge (an STS JWT) to reception as the request itself and receives an access token, because reception trusts the employer’s stamp (the STS JWKS).

Figure 3: IAM_JWT_BEARER. The visitor shows an employer-signed badge (an STS JWT) to reception as the request itself and gets an access token. Reception accepts it because it trusts the employer’s stamp (the STS JWKS).

First, the visitor collects an employer-signed badge: Replicator calls STS GetWebIdentityToken to mint an STS JWT. At the reception desk the badge itself is the request. The visitor shows it to ask for a pass. Reception trusts the employer’s tamper-proof stamp (STS JWKS), so it accepts the badge and prints a temporary access pass. In practice (RFC 7523 §2.1), the STS JWT is sent as the authorization grant (assertion), and the IdP trusts AWS STS as an external token issuer. Use it when you want secretless authentication, and your IdP can trust an external issuer’s JWTs.

Scenario 3: CLIENT_CREDENTIALS_ASSERTION (the same badge, used as ID on the form)
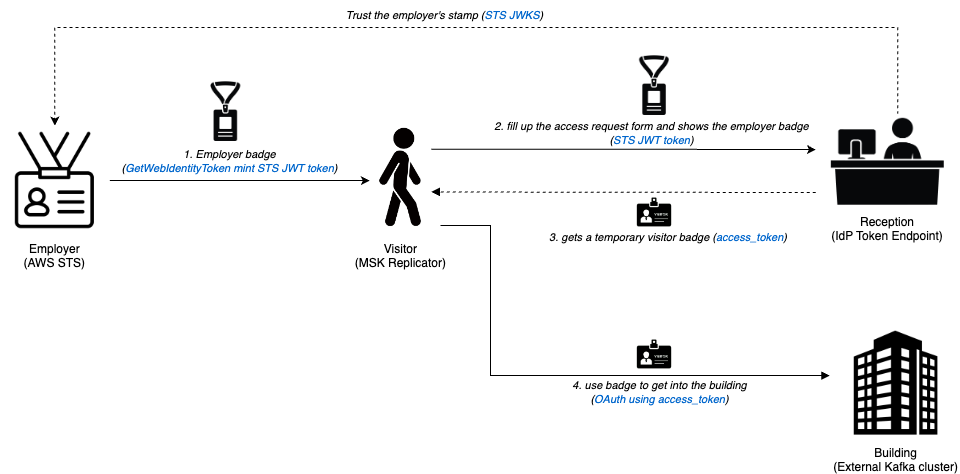
CLIENT_CREDENTIALS_ASSERTION scenario: the visitor fills out reception’s standard request form and attaches the same STS JWT as identification to receive an access token, which reception grants by trusting the employer’s stamp (the STS JWKS).

Figure 4: CLIENT_CREDENTIALS_ASSERTION. The visitor fills out reception’s standard request form and attaches the same STS JWT as ID, getting an access token. Reception trusts the employer’s stamp (the STS JWKS).

The visitor again collects the same employer-signed badge (STS JWT). This time they fill out the reception desk’s standard access request form (the client_credentials grant) and attach the badge to it as identification, all in one submission. Reception trusts the same employer stamp (STS JWKS) and prints a temporary access pass. In practice (RFC 7521/RFC 7523 §2.2), the same STS JWT is sent as the client_assertion on the client_credentials grant, with the IdP trusting STS as the client’s signing authority (private_key_jwt). Use it when you want secretless authentication and your IdP models external workloads as signed-JWT clients.

Scenarios 2 and 3 in one sentence. Both mint the same STS JWT and share the same benefit: nothing shared can leak, because there is no secret. They differ only in where the STS JWT sits in the token request. IAM_JWT_BEARER sends it as the assertion (the badge is the request), while CLIENT_CREDENTIALS_ASSERTION sends it as the client_assertion on a standard client_credentials request (the badge is ID on the form). That single difference is what you register on the IdP: AWS STS as an external token issuer, or as the client’s signing authority.

Solution overview

Now that you can map your setup to a grant type, the next question is where these pieces actually run. MSK Replicator runs on AWS managed infrastructure but attaches elastic network interfaces (ENIs) into the subnets of the target Amazon MSK cluster’s virtual private cloud (VPC) and initiates every connection from there under a Service Execution Role (SER). Those ENIs sit in private subnets that typically have no NAT or internet gateway, so each external dependency needs an explicit network path. The following diagram shows the full topology for an OAuth migration, including the two pieces that are commonly missed: STS Outbound Web Identity Federation (for the secretless grants) and the interface VPC endpoints for STS and Secrets Manager.
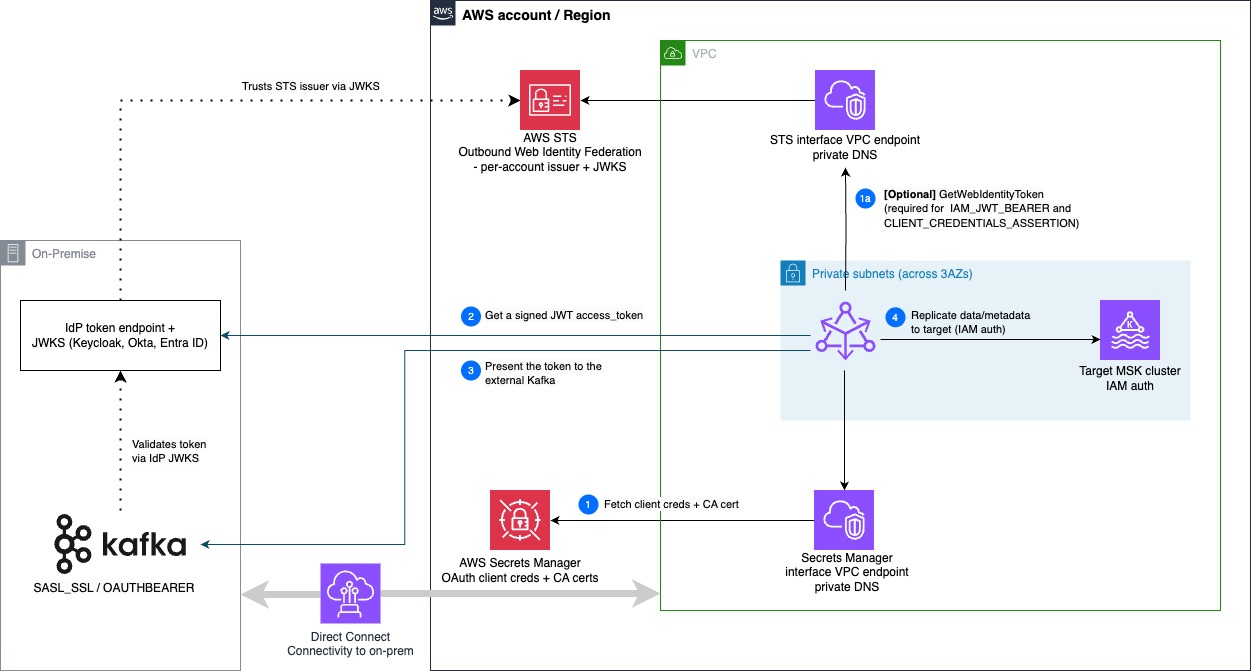
Deployment architecture: the source environment holds the IdP and Kafka brokers; the AWS account holds STS, Secrets Manager, and the Amazon MSK VPC, whose private subnets contain the Replicator ENIs and target cluster, reached through interface VPC endpoints.

Figure 5: Deployment architecture. The source environment holds the IdP and Kafka brokers. The AWS account holds STS, Secrets Manager, and the Amazon MSK VPC, whose private subnets contain the Replicator ENIs and target cluster, reached through interface VPC endpoints.

The source environment (on the left, shown as on-premises here, but it can equally be another cloud or a self-managed cluster on AWS) holds two components: the IdP token endpoint and JWKS (Keycloak, Okta, Entra ID) and the external Kafka brokers on a SASL_SSL / OAUTHBEARER listener. Everything else runs in your AWS account.

The two dotted lines are trust relationships you configure ahead of time, not runtime calls:

  • External Kafka validates token by using IdP JWKS – The broker checks every presented access token against the IdP’s published public keys. This applies to all grants.
  • IdP trusts STS issuer through JWKS – For the secretless grants only, the IdP is configured to trust your account’s STS issuer and validate the STS-signed JWT against STS’s JWKS. When STS Outbound Web Identity Federation is enabled, AWS provisions a per-account issuer URL (https://<id>.tokens.sts.global.api.aws) whose JWKS the IdP trusts. This trust is not used by CLIENT_CREDENTIALS.

The numbered arrows are the runtime flow, all originating from the Replicator ENIs:

  • Step 1: Fetch client credentials and the CA certificate from AWS Secrets Manager, through its VPC endpoint. For CLIENT_CREDENTIALS this includes the client_id/client_secret. For the secretless grants it is only the CA certificate(s).
  • Step 1a (optional): Call GetWebIdentityToken on AWS STS, through the STS VPC endpoint, to mint a JWT of Replicator’s AWS identity. Required only for IAM_JWT_BEARER and CLIENT_CREDENTIALS_ASSERTION.
  • Step 2: Get a signed JWT access token from the IdP token endpoint, exchanging either the client secret or the STS JWT depending on the grant.
  • Step 3: Present the token to the external Kafka brokers over SASL/OAUTHBEARER.
  • Step 4: Replicate to the target Amazon MSK cluster using IAM authentication.

The two supporting pieces inside the VPC, the Secrets Manager and STS interface VPC endpoints, are commonly overlooked precisely because the private subnets have no NAT or internet gateway. We cover exactly why they’re needed, and when, in the following section, Cross-cutting requirements.

Configuring and creating the replicator

With the architecture in mind, you can now configure Replicator itself. MSK Replicator models OAuth through a saslOAuthBearer structure on the external cluster’s clientAuthentication. Exactly one of three mechanism members must be present: clientCredentials, iamJwtBearer, or clientCredentialsAssertion. The control plane enforces this mutual exclusivity. Fields shared across all three (tokenEndpointUrl, scope, tokenEndpointAuthenticationMethod, tokenEndpointTlsCertificateArn, and saslExtensions) live at the saslOAuthBearer level.

Before the per-grant details, here are the requirements that apply to every OAuth migration, whichever grant you choose. Most OAuth setup failures trace back to one of these, so review them first.

Cross-cutting requirements

Here are the five items that apply to every grant: TLS trust, secret format, network reachability, the Service Execution Role, and STS federation.

a) TLS everywhere, and two separate trust settings

Replicator connects to two TLS endpoints, and they are configured independently:

  • encryptionInTransit.rootCaCertificate: the CA that signed your Kafka brokers’ TLS certificates (the SASL_SSL listener – :9096).
  • tokenEndpointTlsCertificateArn: the CA that signed your IdP’s token endpoint TLS certificate (for example – Keycloak on :8443).

If your broker and IdP are signed by the same private CA, you still must supply the CA in both fields. Omitting tokenEndpointTlsCertificateArn when the IdP uses a private or self-signed cert produces a PKIX path building failed error during token acquisition. Because that fails before workers stabilize, you’ll see a generic failure with no worker logs. If your IdP uses a publicly-trusted certificate (for example, it sits behind a public endpoint), you can omit tokenEndpointTlsCertificateArn entirely.

b) Secret format: store key/value pairs, not raw values

Every secret Replicator reads (client credentials, CA certificate) is parsed by the config provider as a set of key/value pairs. Use the Secrets Manager console’s Key/value editor rather than pasting raw text, and it will serialize and escape the values for you.

The keys the provider expects:

Key Value Used for
certificate the CA in PEM (newlines escaped as \n) CA-certificate secrets (rootCaCertificate, tokenEndpointTlsCertificateArn)
client_id, client_secret your OAuth client credentials the CLIENT_CREDENTIALS token-request secret

Custom parameters, headers, and SASL extensions. Some IdPs require extra data on the token request, and some brokers require SASL/OAUTHBEARER extensions. The config provider supports both through reserved key prefixes in the same secret:

Prefix Effect Example key Example value
custom_param. adds a parameter to the token request sent to the IdP custom_param.tenant_token myTenantToken
custom_header. adds an HTTP header to the IdP token request custom_header.X-Tenant-Id acme
extension. adds a SASL/OAUTHBEARER extension presented to the broker (for example, Confluent Cloud’s logicalCluster) extension.logicalCluster myLogicalClusterId

For example, an IdP that expects a tenant token as a request parameter and a Confluent Cloud broker that requires a logical-cluster extension would add custom_param.tenant_token and extension.logicalCluster as extra key/value pairs alongside client_id/client_secret in the same secret.

c) Network reachability from Replicator’s ENIs

Replicator attaches ENIs into the subnets you specify (through the target amazonMskCluster cluster’s vpcConfig) and initiates all connections from there. Those ENIs must be able to reach:

  1. Your external brokers, over VPC peering, AWS Transit Gateway, AWS Direct Connect, or VPN, with security groups permitting the SASL_SSL port.
  2. Your IdP’s token endpoint, over the same networking. The endpoint hostname must resolve from those subnets.
  3. AWS Secrets Manager, to fetch credentials/CA. If the subnets have no NAT/internet gateway, add an interface VPC endpoint for com.amazonaws.<region>.secretsmanager with private DNS.
  4. AWS STS (only for IAM_JWT_BEARER and CLIENT_CREDENTIALS_ASSERTION), to call GetWebIdentityToken. In no-egress subnets this will time out (STS GetWebIdentityToken call failed: Connect timed out) unless you add an interface VPC endpoint for com.amazonaws.<region>.sts with private DNS. This is the most common oversight for the secretless grants.

Both endpoints use private DNS, so the standard secretsmanager.<region>.amazonaws.com and sts.<region>.amazonaws.com hostnames resolve to the endpoint inside the VPC, with no client change needed.

A note on vpcConfig placement. For an external Apache Kafka cluster, vpcConfig is specified on the target amazonMskCluster entry, not the external apacheKafkaCluster entry. The API rejects a vpcConfig on the external cluster. The ENIs it creates are what reach both clusters and all AWS endpoints.

d) The Service Execution Role (SER)

Replicator assumes an IAM role to do its work. Two parts matter:

  • Trust policy – Must allow the Replicator service to assume it. kafka.amazonaws.com needs to be trusted. A trust policy that is too narrow fails with AccessDenied.ServiceExecutionRoleUnassumable.
  • Permissions – The replication permissions are extensive and depend on which features you enable, so follow the service execution role permissions reference to build a least-privilege policy.

e) Enabling STS Outbound Web Identity Federation (secretless grants only)

For IAM_JWT_BEARER and CLIENT_CREDENTIALS_ASSERTION, sts:GetWebIdentityToken must be enabled for your account/role. When enabled, AWS provisions a dedicated issuer URL of the form https://<uuid>.tokens.sts.global.api.aws. Every JWT STS mints for your account carries this as its iss claim, and its public keys are published under this issuer’s JWKS. You configure your IdP to trust this issuer. Granting the sts:GetWebIdentityToken IAM action is necessary but not sufficient. The account-level federation feature must also be turned on.

Create the replicator

A repeatable way to create the replicator is with a request file and --cli-input-json, so you can keep the full configuration under version control. The following example is a complete CLIENT_CREDENTIALS request. The two secretless variants change only the saslOAuthBearer block (shown after).

aws kafka create-replicator \
  --region <region> \
  --cli-input-json file://create-replicator.json

create-replicator.json:

{
  "replicatorName": "oauth-migration-replicator",
  "serviceExecutionRoleArn": "arn:aws:iam::<acct>:role/msk-replicator-execution-role",
  "kafkaClusters": [
    {
      "apacheKafkaCluster": {
        "apacheKafkaClusterId": "<source-cluster-id>",
        "bootstrapBrokerString": "b-1.ext-kafka.example.com:9096,b-2.ext-kafka.example.com:9096"
      },
      "clientAuthentication": {
        "saslOAuthBearer": {
          "tokenEndpointUrl": "https://idp.example.com/realms/kafka/protocol/openid-connect/token",
          "clientCredentials": {
            "tokenRequestSecretArn": "arn:aws:secretsmanager:<region>:<acct>:secret:<oauth-creds>"
          },
          "tokenEndpointAuthenticationMethod": "POST",
          "tokenEndpointTlsCertificateArn": "arn:aws:secretsmanager:<region>:<acct>:secret:<idp-ca>"
        }
      },
      "encryptionInTransit": {
        "encryptionType": "TLS",
        "rootCaCertificate": "arn:aws:secretsmanager:<region>:<acct>:secret:<broker-ca>"
      }
    },
    {
      "amazonMskCluster": {
        "mskClusterArn": "arn:aws:kafka:<region>:<acct>:cluster/target-msk/<uuid>"
      },
      "vpcConfig": {
        "subnetIds": [
          "subnet-aaaa",
          "subnet-bbbb",
          "subnet-cccc"
        ],
        "securityGroupIds": [
          "sg-xxxxxxxx"
        ]
      }
    }
  ],
  "replicationInfoList": [
    {
      "sourceKafkaClusterId": "<source-cluster-id>",
      "targetKafkaClusterArn": "arn:aws:kafka:<region>:<acct>:cluster/target-msk/<uuid>",
      "targetCompressionType": "NONE",
      "topicReplication": {
        "topicsToReplicate": [
          ".*"
        ],
        "detectAndCopyNewTopics": true,
        "copyTopicConfigurations": true
      },
      "consumerGroupReplication": {
        "consumerGroupsToReplicate": [
          ".*"
        ],
        "detectAndCopyNewConsumerGroups": true,
        "synchroniseConsumerGroupOffsets": true
      }
    }
  ]
}

Field names and exact nesting follow the create-replicator API reference. Check it for the full schema and any Region-specific values.

The example above uses CLIENT_CREDENTIALS. For the full schema, any Region-specific values, and detailed examples for the other grant types, check the MSK documentation.

With the requirements and configuration in hand, here is the order to put them in:

  1. Pick your grant type using the preceding decision table. CLIENT_CREDENTIALS is the fastest path if you already manage a client secret. Otherwise choose a secretless grant based on how your IdP models external workloads. For a multi-hop internal chain, use IAM_JWT_BEARER against the proxy pattern described in the next section.
  2. Prepare the IdP: create the client (or the STS-trust configuration), and note the exact token endpoint URL and issuer.
  3. Stage secrets in Secrets Manager, as JSON (requirement b): client credentials (if any) and the CA certificate(s).
  4. Wire the network (requirement c): connectivity from Replicator’s subnets to your brokers and IdP, plus interface VPC endpoints for Secrets Manager and (secretless grants only) STS, both with private DNS.
  5. [Optional but recommended]: Smoke-test the path from inside the VPC – IdP setup is often the part that takes the most iterations, and Replicator provisioning is a slow way to discover a misconfigured token endpoint or a missing TLS trust. Spin up a small EC2 instance in Replicator’s subnets, install a Kafka client, and run an end-to-end produce/consume against the external brokers using SASL/OAUTHBEARER (a client_credentials flow is simplest). This validates the three things most likely to be wrong (network reachability to the IdP and brokers, both TLS trusts for the broker CA and IdP CA, and token vending) while you can still fix them in seconds. Tear the instance down once the round trip works.
  6. Enable STS Outbound Web Identity Federation (requirement e. Secretless grants only) and configure your IdP to trust the resulting issuer.
  7. Build the SER (requirement d) with a trust policy the Replicator service can assume and the required permissions.
  8. Create the replicator with the create-replicator request for your grant. Remember both TLS trust fields for a private-CA IdP (requirement a), and vpcConfig on the target entry only.
  9. Verify – Produce to a topic on the external cluster and confirm the records land on the target (consume with IAM auth on the Amazon MSK side). Then watch the health signals:
    • In the Amazon MSK console, the replicator should reach the RUNNING state.
    • In Amazon CloudWatch, under the AWS/Kafka namespace, watch the replicator’s ReplicationLatency and MessageLag metrics. Both should be low and stable, and MessageLag should trend toward zero as it catches up.
    • A healthy replicator commits offsets continuously. A steady “1 message per batch” with no producer activity is only the internal heartbeat topic, not a stall.

Handling an additional identity layer: the federation-proxy pattern

Who owns what – Before the details, the ownership line is simple and worth stating up front:

  • What Replicator guarantees: it calls the configured tokenEndpointUrl with the configured grant, includes the STS JWT, expects a standard {access_token, token_type, expires_in} response, and refreshes before expiry.
  • What you own: everything at and behind the proxy, including validating the STS JWT, the downstream token exchanges, claim mapping, and the availability and latency of the endpoint. The proxy runs in your VPC and is owned entirely by you.

So far we have assumed you can point Replicator at a single token endpoint. Some organizations can’t. Instead, they have an internal identity chain: several hops of token exchange and federation that a workload must traverse before it holds a token the Kafka brokers accept.

A representative example is a large financial institution whose chain has several hops: an AWS workload’s identity (a signed GetCallerIdentity request) is exchanged at an internal Token Exchange service for an intermediate JWT, which an internal IdP then consumes as a client_assertion to issue the final Bearer token the Kafka brokers accept.

Replicator connects to a single HTTPS token endpoint using one of the three grant types and expects a standard token response. When the identity flow spans multiple hops like this, you place a proxy in front of that chain so Replicator still sees a single endpoint.

The solution: a customer-owned proxy

You deploy a small proxy in your own VPC that collapses the chain behind a single endpoint. From Replicator’s perspective, this is an ordinary OAuth flow against one token endpoint. Everything behind that endpoint is opaque to Replicator and owned entirely by you.

The grant Replicator uses to reach the proxy is a separate choice from the exchanges happening behind it. We recommend a secretless grant (IAM_JWT_BEARER or CLIENT_CREDENTIALS_ASSERTION) so there is no long-lived secret between Replicator and the proxy. CLIENT_CREDENTIALS is also valid if you would rather the proxy authenticate Replicator with a client secret. The following walkthrough uses IAM_JWT_BEARER, where the proxy validates the STS JWT that Replicator presents.

How it works, end to end. The following sequence diagram traces the full token exchange, from Replicator’s request to the Bearer it finally presents to the external Kafka brokers.
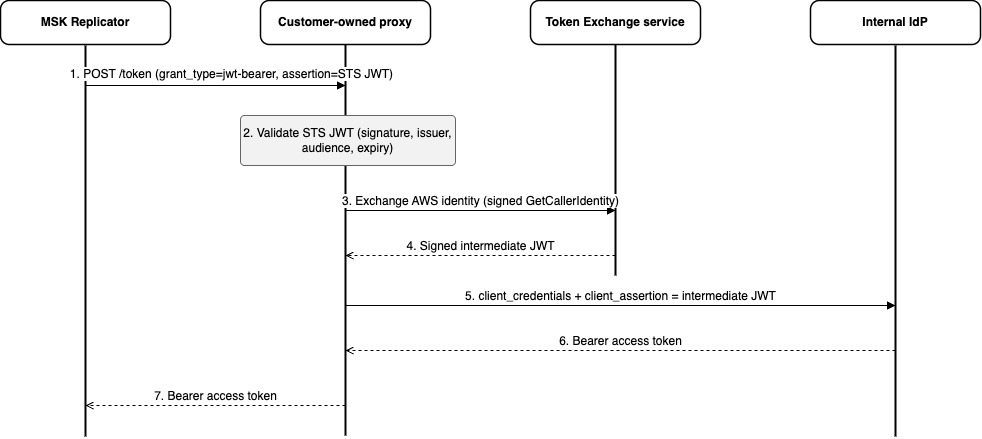
Federation-proxy token flow: the proxy validates Replicator’s STS JWT, exchanges its own AWS identity at the Token Exchange service for an intermediate JWT, presents that to the internal IdP, and returns the resulting Bearer token to Replicator.

Figure 6: Federation-proxy token flow. The proxy validates Replicator’s STS JWT, exchanges its own AWS identity at the Token Exchange service for an intermediate JWT, presents that to the internal IdP, and returns the resulting Bearer to Replicator.

  1. Replicator to proxy – Replicator POSTs its STS JWT as assertion to the proxy’s token endpoint, a plain IAM_JWT_BEARER request (grant_type=jwt-bearer). Because the endpoint is private, Replicator reaches it through an execute-api interface VPC endpoint, the same private-connectivity approach used for Secrets Manager and STS. (Replicator first obtains the STS JWT by calling STS GetWebIdentityToken through the STS VPC endpoint.)
  2. Proxy validates the STS JWT (signature against STS’s JWKS, plus iss/aud/exp/sub checks. The sub is the caller’s AWS ARN).
  3. Proxy to Token Exchange service – The proxy exchanges its own AWS identity, presented as a signed GetCallerIdentity request, at the internal Token Exchange service.
  4. Token Exchange service → proxy – It returns a signed intermediate JWT.
  5. Proxy to internal IdP – The proxy makes a client_credentials request that carries the intermediate JWT as the client_assertion.
  6. Internal IdP to proxy – The IdP issues the final Bearer access token.
  7. Proxy to Replicator – The proxy returns the Bearer, and Replicator presents it to the external brokers over SASL/OAUTHBEARER. The brokers validate it against the final IdP’s JWKS, a completely ordinary OAuth handshake from their point of view.

Reference architecture

Here is the reference architecture for the end-to-end solution.
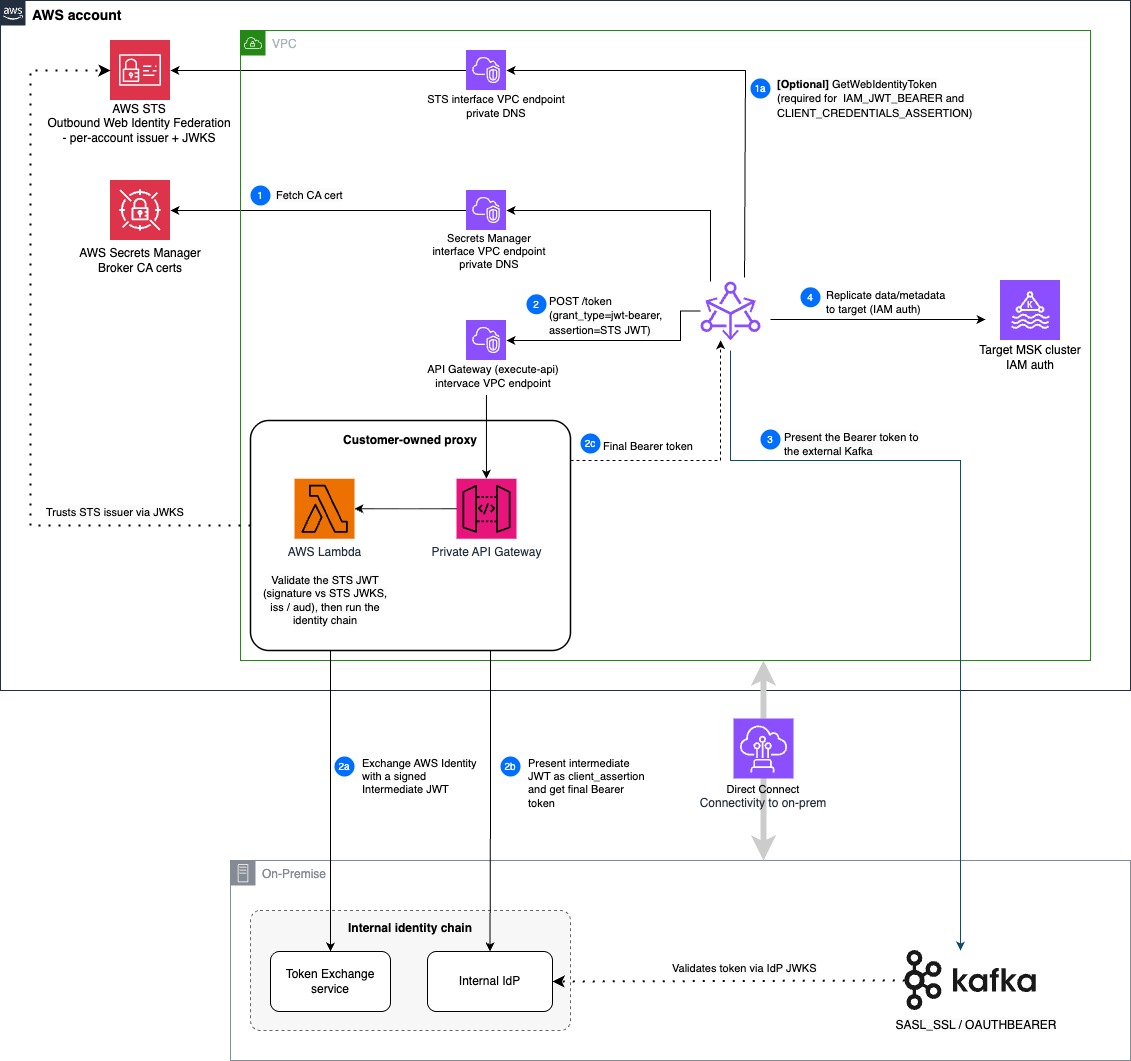
Federation-proxy reference architecture: Replicator ENIs in a private subnet call a customer-owned proxy (a Lambda function behind a private API Gateway) that runs the on-premises identity chain over Direct Connect before Replicator replicates into the target Amazon MSK cluster.

Figure 7: Federation-proxy reference architecture. Replicator ENIs in a private subnet call a customer-owned proxy (a Lambda behind a private API Gateway), which runs the on-premises identity chain over Direct Connect before Replicator replicates into the target Amazon MSK cluster.

Everything on the Replicator side runs in your VPC’s private subnets: the Replicator ENIs, the customer-owned proxy, and the target Amazon MSK cluster. The proxy here is an AWS Lambda function behind a private Amazon API Gateway, but it can run on any compute you prefer (EC2, ECS, or EKS) as long as it exposes a single private HTTPS token endpoint. Connectivity to the on-premises Token Exchange service, internal IdP, and Kafka brokers runs over AWS Direct Connect (a VPN or VPC peering works too).

The outer legs of this flow are exactly the base migration from Solution overview: step 1 (fetch the broker CA from Secrets Manager), step 1a (mint the STS JWT through STS), step 3 (present the Bearer to the brokers), and step 4 (replicate to the target with IAM). What’s new here is the proxy hop in the middle, which replaces the single “step 2” call to a token endpoint:

  • 2. POST /token – Replicator sends the STS JWT as the assertion to the proxy’s private token endpoint, reached through the execute-api interface VPC endpoint. The proxy validates it against STS’s JWKS.
  • 2a. Exchange AWS identity – The proxy presents its own AWS identity (a signed GetCallerIdentity request) to the internal Token Exchange service and gets back a signed intermediate JWT.
  • 2b. Present as client_assertion The proxy sends a client_credentials request to the internal IdP with the intermediate JWT as the client_assertion, and receives the final Bearer.
  • 2c. Final Bearer token – The proxy returns the Bearer to Replicator, which then continues at step 3.

As in the base architecture, the dotted lines are prerequisite trust relationships, not runtime calls: the proxy trusts AWS STS as an issuer (validating the STS JWT against STS’s JWKS), and the Kafka brokers validate the final Bearer against the internal IdP’s JWKS.

One subtlety worth calling out is the split of TLS trust. Replicator connects directly only to the private API Gateway (which uses a publicly trusted certificate) and to the Kafka brokers, so the only certificate it fetches from Secrets Manager is the broker CA. The internal IdP’s CA is the proxy’s concern: the proxy terminates TLS to the Token Exchange service and internal IdP, so it carries their CA material, not Replicator.

The same single-endpoint pattern handles other “extra layer” scenarios without any Replicator change: claim enrichment (the proxy intercepts and augments), rate-limited IdPs (the proxy caches tokens), IdPs requiring mTLS (the proxy terminates Replicator’s HTTPS and initiates mTLS onward), and IdP migrations (swap the proxy’s target without touching Replicator config).

A working reference implementation of this customer-owned proxy is available at GitHub.

Conclusion

In this post, we walked through how to migrate a self-managed, OAuth-authenticated Apache Kafka cluster to Amazon MSK using MSK Replicator: how the SASL/OAUTHBEARER handshake works, how to map your identity provider to one of the three supported grant types, the deployment architecture and prerequisites that the connection depends on, and how to handle identity providers that sit behind an additional federation layer. To get started, see the Amazon MSK Developer Guide and the Amazon MSK Replicator documentation. For the federation-proxy example, see the sample implementation on GitHub.
About the author

Subham Rakshit

Subham Rakshit

Subham is a Streaming Solutions Architect for Analytics at AWS based in the UK. He works with customers to design and build search and streaming data platforms that help them achieve their business objective. Outside of work, he enjoys spending time solving jigsaw puzzles with his daughters.
Announcing in-place ZooKeeper-to-KRaft cluster upgrades for Amazon MSK

Post Syndicated from Austin Groeneveld original https://aws.amazon.com/blogs/big-data/announcing-in-place-zookeeper-to-kraft-cluster-upgrades-for-amazon-msk/

Apache Kafka 4.0 officially removes ZooKeeper. If your Amazon Managed Streaming for Apache Kafka (Amazon MSK) Provisioned clusters still run in ZooKeeper metadata mode, now is the time to plan your migration. Amazon MSK now supports in-place upgrades from ZooKeeper to KRaft metadata mode, so you can modernize your existing cluster’s metadata management through the familiar version upgrade workflow.

For more than a decade, Apache ZooKeeper provided dependable metadata management for Kafka, including controller election, partition state, broker registration, and topic configuration. With Apache Kafka 4.0, ZooKeeper is officially removed in favor of KRaft, an embedded Raft-based consensus protocol that handles metadata management internally. It brings those responsibilities into Apache Kafka itself, creating a more streamlined foundation for the continued evolution of Kafka. Amazon MSK has supported KRaft-mode clusters since May 2024, and all Kafka 4.x versions on Amazon MSK use KRaft.

With the in-place upgrade, you can retain your cluster data and metadata while Amazon MSK manages the control-plane transition. Your cluster remains available for produce and consume traffic throughout the process, with no expected downtime if you’re following best practices. By using the existing version upgrade workflow, the move to KRaft becomes a natural step in your cluster’s lifecycle. This prepares your cluster for Kafka 4.x and future Kafka releases.

Prerequisites

Before initiating the upgrade, review the following requirements to confirm your cluster is ready for the transition.

Supported source versions

Clusters must be running Kafka 3.9.x in ZooKeeper mode to use the in-place upgrade. If your cluster is running an earlier version, such as 3.6.0, 3.7.x, or 3.8.x, first complete a standard in-place version upgrade to 3.9.x. You can then initiate the upgrade to 3.9.x.kraft.

Kafka 3.9 is the bridge release for this transition because it supports both ZooKeeper and KRaft modes. To support customers through this migration process, Amazon MSK provides extended support for 3.9.x for a minimum of 2 years from its April 2025 release.

Client compatibility

Requirement Detail
Minimum client library Apache Kafka client v3.0+
Recommended client version v3.9 or above
Connection strings Must use bootstrap.servers only. Any ZooKeeper connection strings (the --zookeeper flag) must be removed before upgrade.

The --zookeeper admin flag was deprecated in Kafka 2.5 and removed in 3.0. Before upgrading, update any remaining applications or tools that connect directly to ZooKeeper.

Pre-upgrade checklist

Before beginning the upgrade, confirm the following:

  • For Standard brokers, the cluster must be deployed across three Availability Zones. Express brokers provide this by default.
  • The cluster is running Kafka 3.9.x in ZooKeeper mode.
  • Standard brokers expose direct ZooKeeper access on ports 2181 (plaintext) and 2182 (TLS). Before upgrading, validate that you’ve disabled ZooKeeper access on the cluster and none of your applications rely on these connections.
  • Solutions using dynamic Kafka configurations that relied on ZooKeeper have been removed before attempting the upgrade operation.
    • If you previously configured custom domain names on a ZooKeeper-based deployment using the dynamic override (kafka-configs.sh --alter on advertised.listeners), be aware that KRaft does not support this dynamic configuration. If you attempt to upgrade your MSK cluster to KRaft with altered advertised.listeners, the upgrade operation fails.
    • If you’re implementing your custom domain name solution on MSK moving forward with KRaft, we recommend our coinciding MSK release for custom domain name support by statically configuring the custom.advertised.listeners property through the UpdateClusterConfiguration API.
  • The cluster has no under-replicated partitions.
  • The cluster is running within per-broker partition limits for standard or express broker clusters.
  • For clusters running above the KRaft brokers-per-cluster limit, you might need an additional quota increase. If you previously raised a quota increase for your ZooKeeper brokers-per-cluster, submit another quota increase for the KRaft limit before attempting the upgrade.
  • The cluster has enough reserve capacity to support rolling broker restarts while serving client traffic.
  • As a best practice, verify that monitoring is ready for the transition from ZooKeeper-specific metrics to KRaft controller metrics.
    • After the migration, ZooKeeper-specific Amazon CloudWatch metrics such as ZookeeperRequestLatencyMsMean and ZookeeperSessionState are no longer available.
    • If you use Open Monitoring, Kafka also stops publishing ZooKeeper metrics. Plan to update or retire related alerts and dashboards as part of your migration preparation.

How the upgrade works

When you initiate the upgrade, Amazon MSK performs a managed, multi-phase migration:

  1. Controller quorum bootstrap: Amazon MSK provisions KRaft controller nodes alongside the existing ZooKeeper infrastructure. Both systems operate in parallel during this phase.
  2. Metadata migration: The KRaft controller reads the cluster state from ZooKeeper and writes it to the internal KRaft metadata log.
  3. Broker transition: Amazon MSK performs a rolling update and registers with the KRaft controller quorum. Data plane operations remain available during the transition.
  4. Validation and bake period: Amazon MSK verifies cluster health under KRaft, including partition leadership, replication state, and controller responsiveness.
  5. ZooKeeper decommissioning: After validation succeeds, Amazon MSK removes the ZooKeeper infrastructure and the cluster operates entirely in KRaft mode.

During the upgrade, the cluster enters UPDATING state. You can continue producing and consuming data, while Amazon MSK administrative API operations are temporarily unavailable until the cluster returns to ACTIVE.

Amazon MSK maintains a high bar for durability during the transition. It uses rigorous safety checks at each phase of the migration to protect customer metadata in both roll-forward and rollback scenarios.

Built-in recovery

Amazon MSK monitors cluster health throughout the upgrade. If it detects a condition that prevents the migration from completing, it automatically returns the cluster to its pre-migration state. No customer action is required during recovery.

The operation status changes to Reverting to pre-migration state while Amazon MSK restores the original Kafka version and reconnects ZooKeeper. After the cluster returns to ACTIVE, the describe-cluster-operation API provides error codes, failure reasons, and recommended remediation steps. You can use these to address the issue before starting the upgrade again.

How to perform the upgrade

The following steps walk you through the upgrade process using the Amazon MSK console. You can also perform these steps programmatically using the AWS Command Line Interface (AWS CLI) or SDK.

Step 1: Disable ZooKeeper access (standard brokers only)

Note: This step applies only to Standard broker clusters. Express broker clusters don’t expose direct ZooKeeper access and can skip directly to Step 2.

Standard brokers expose direct ZooKeeper access on ports 2181 (plaintext) and 2182 (TLS). Before upgrading, validate that none of your applications rely on these connections.

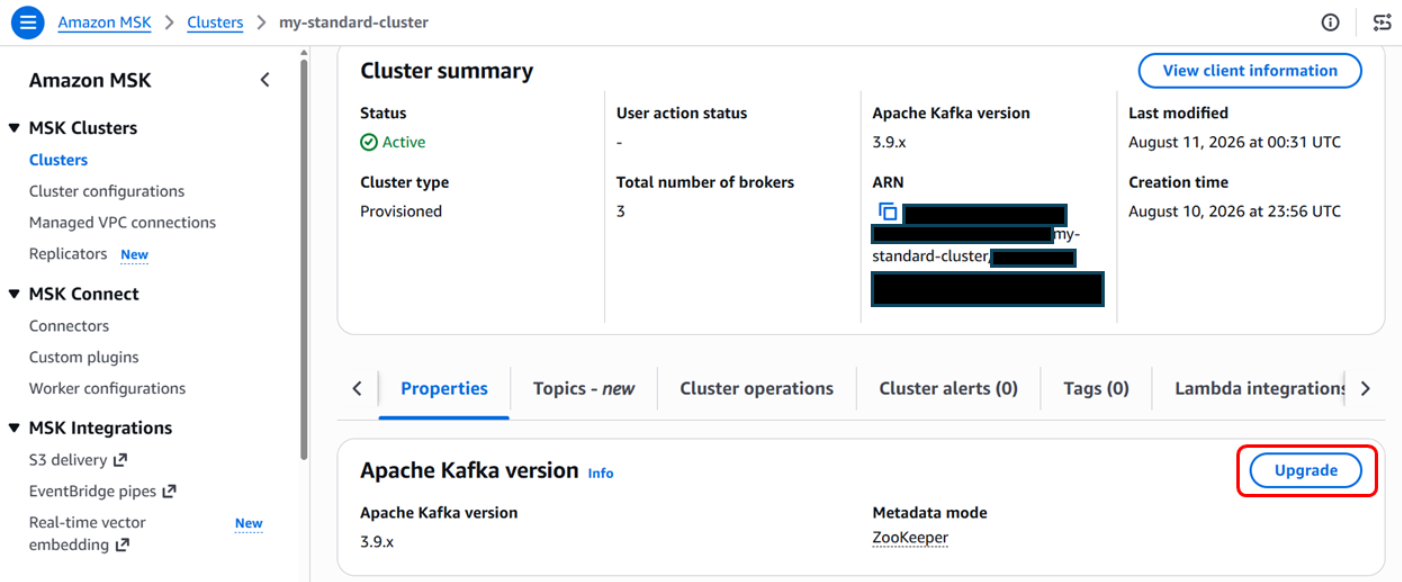
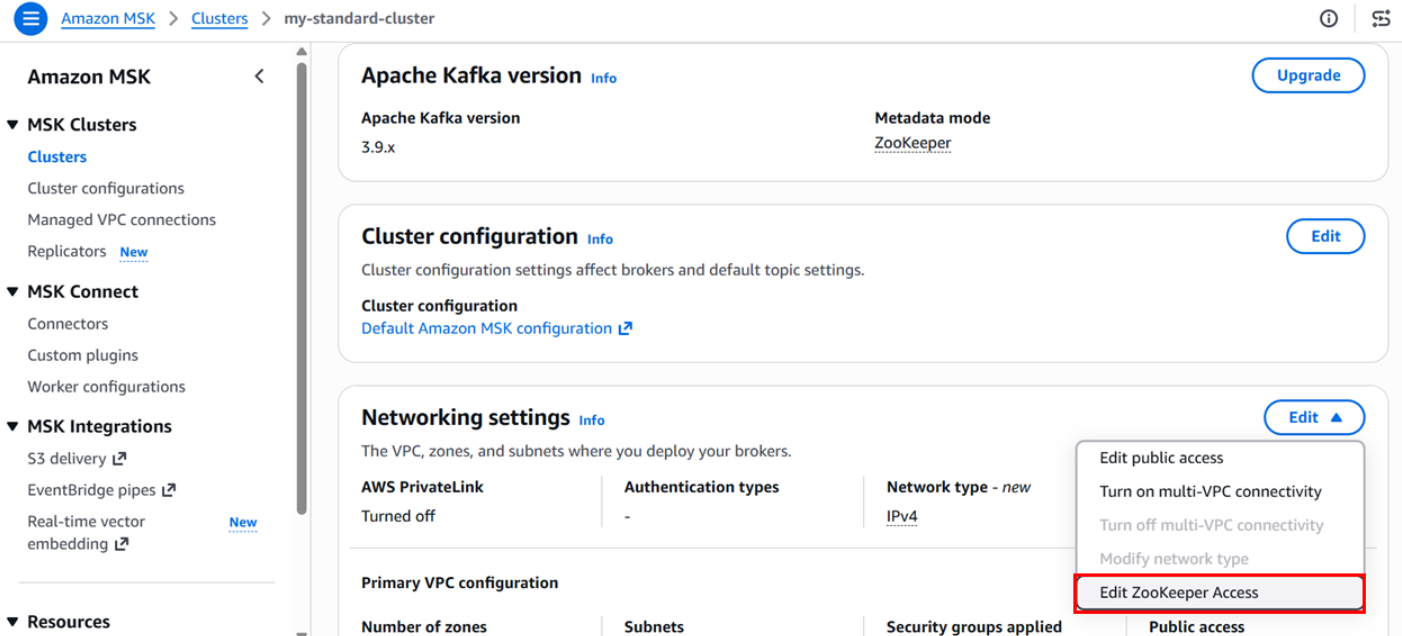
Navigate to your cluster’s Properties tab, choose Network settings, and then choose Edit ZooKeeper access.

Figure 1: Editing ZooKeeper access from the cluster network settings

Figure 1: Editing ZooKeeper access from the cluster network settings

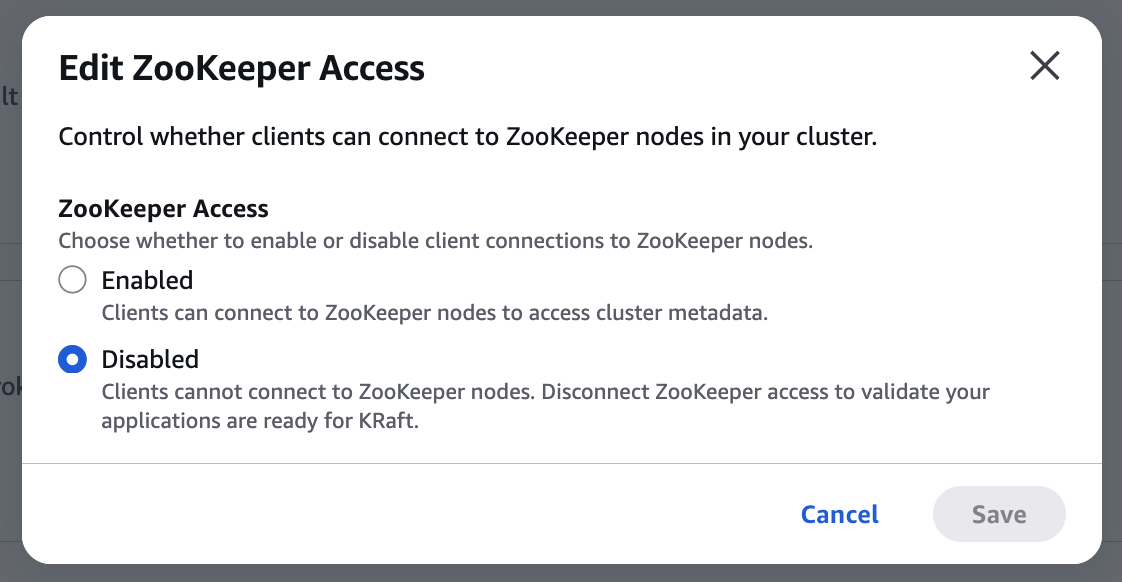
In the pop-up window, verify that ZooKeeper access is set to Disabled, and then choose Save.

Edit ZooKeeper access dialog with access set to Disabled and the Save button

Figure 2: Confirming ZooKeeper access is disabled

Confirm that producers, consumers, and admin tooling continue operating normally without ZooKeeper connectivity. This step is fully reversible. Re-enable ZooKeeper access immediately if anything breaks.

Figure 3: Verifying client traffic continues without ZooKeeper access

Step 2: Initiate the version upgrade

In the Amazon MSK console, under Properties, choose Upgrade in the Apache Kafka version section.

Figure 4: Starting a version upgrade from the Apache Kafka version section

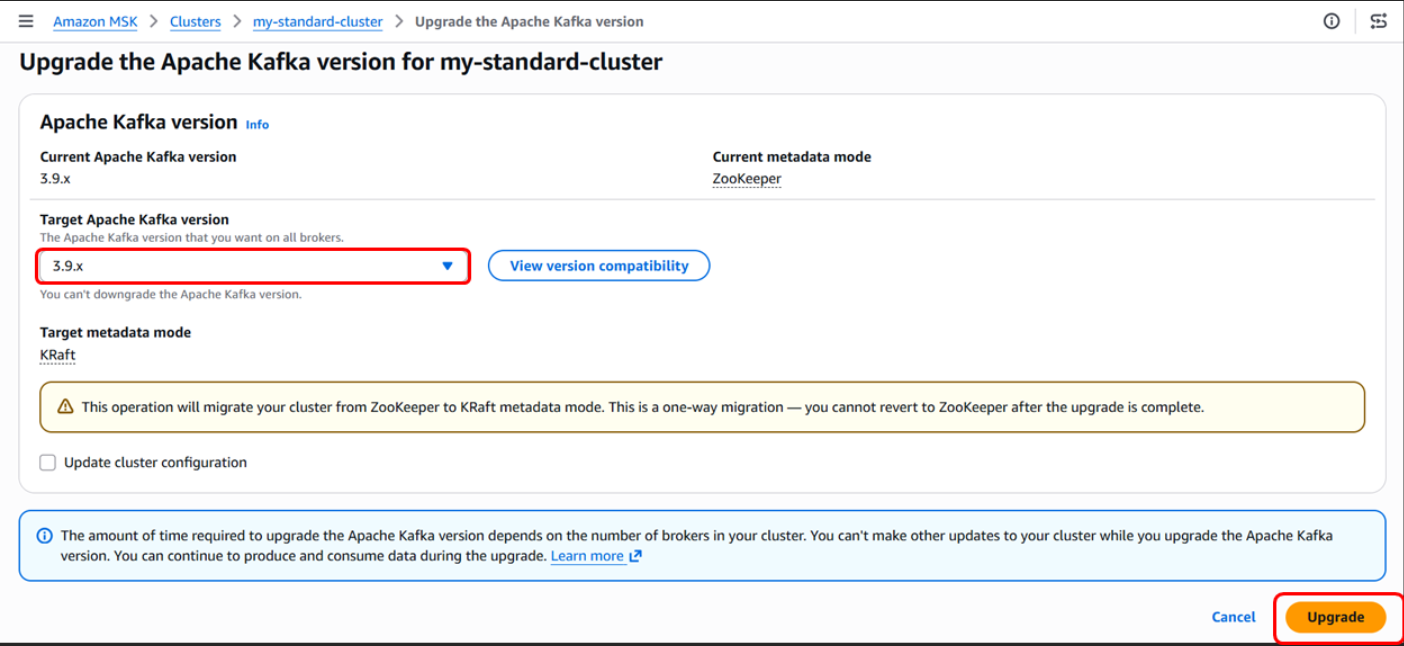
Select your cluster and start a version upgrade to 3.9.x with Target metadata mode set to KRaft. Choose Upgrade.

Figure 5: Selecting KRaft as the target metadata mode

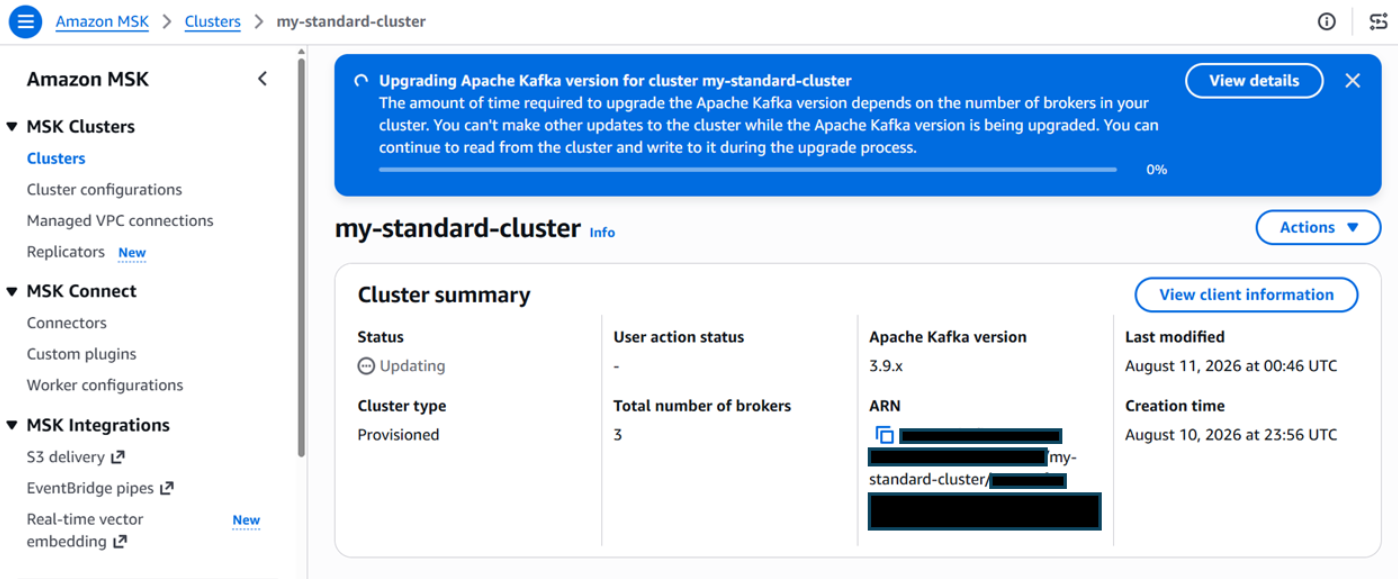
You can monitor your upgrade progress on the cluster properties page.

Figure 6: Monitoring upgrade progress on the cluster properties page

Step 3: Monitor upgrade progress

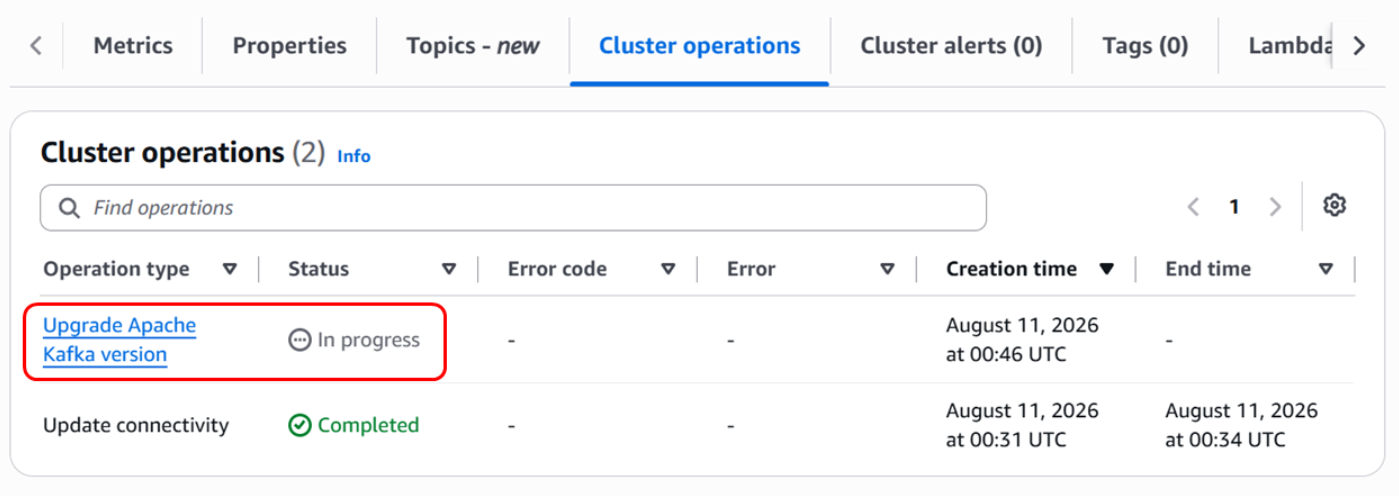
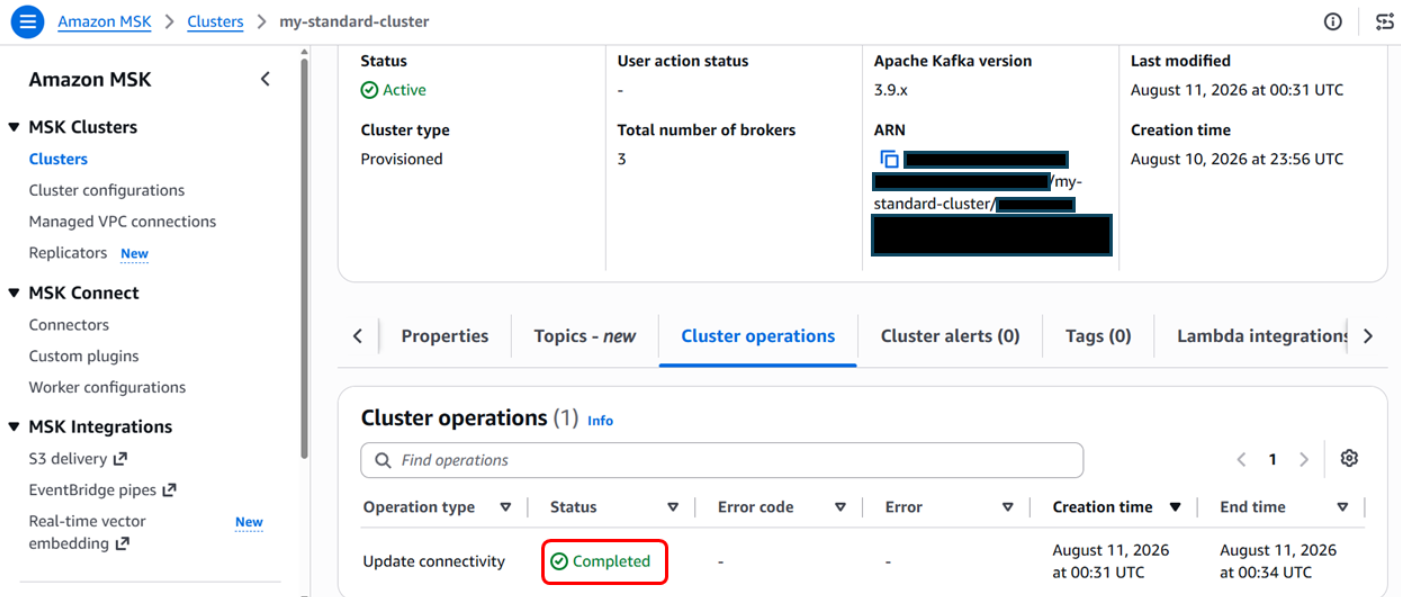
Track progress on the Cluster operations tab in the Amazon MSK console or with the describe-cluster-operation API.

Figure 7: Tracking the upgrade on the Cluster operations tab

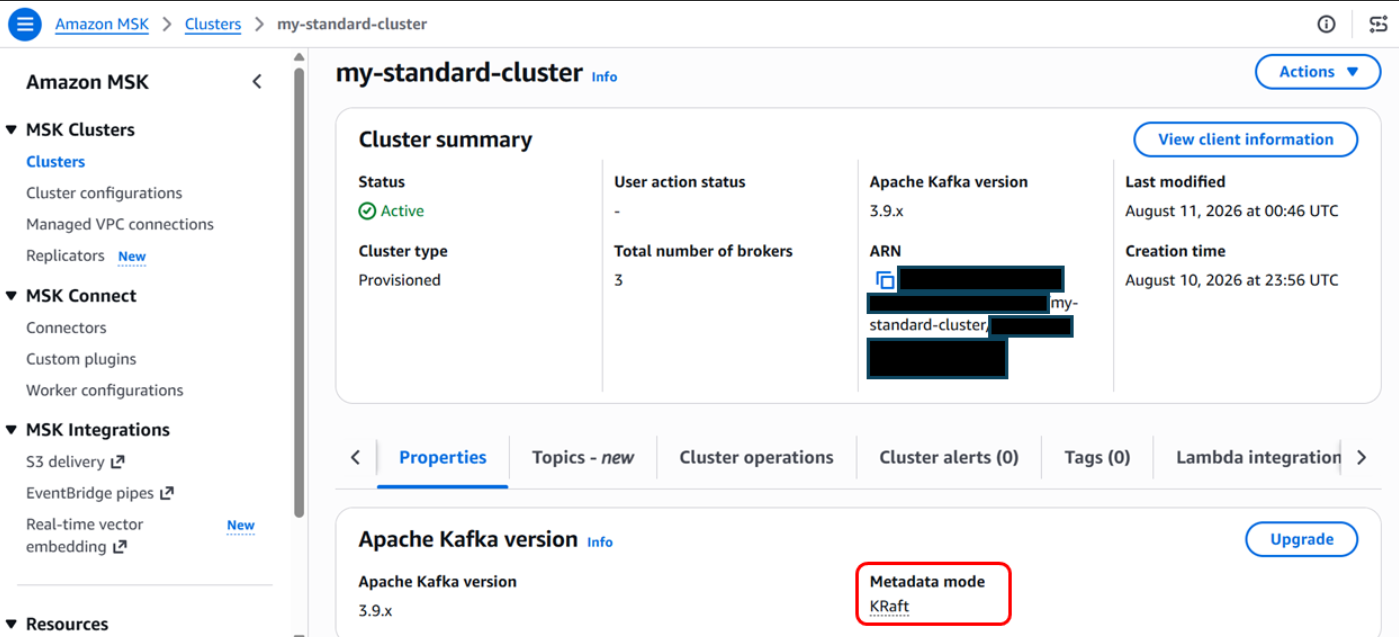
Step 4: Validate the KRaft cluster

After the cluster returns to ACTIVE state in KRaft mode:

  • Verify that topics, partitions, and consumer groups are present.
  • Confirm producer and consumer throughput aligns with pre-migration baselines.
  • Update or disable any ZooKeeper-specific monitoring alerts.
  • Update operational documentation and runbooks to reflect KRaft mode.

Figure 8: Cluster running in KRaft mode after the upgrade

After the upgrade completes, your cluster appears in an Active state with KRaft enabled as the metadata mode.

Get ready for the next generation of Kafka on Amazon MSK

The in-place ZooKeeper-to-KRaft mode upgrade makes it straightforward to prepare existing Amazon MSK clusters for the future of Apache Kafka. Beyond removing external metadata dependencies, KRaft delivers faster failover times and higher partition limits per cluster. Amazon MSK handles the entire metadata transition, rolling broker updates, validation, and recovery workflow for you. With the new in-place experience, you have a clear, streamlined path to upgrade on your schedule and unlock enhanced scalability and resilience.

For more details, see the Amazon MSK Developer Guide and the supported Kafka versions documentation.


About the authors

Austin Groeneveld

Austin Groeneveld

Austin is a Streaming Specialist Solutions Architect at Amazon Web Services (AWS), based in the San Francisco Bay Area. In this role, Austin is passionate about helping customers accelerate insights from their data using the AWS platform. He is particularly fascinated by the growing role that data streaming plays in driving innovation in the data analytics space. Outside of his work at AWS, Austin enjoys watching and playing soccer, traveling, and spending quality time with his family.

Ashley Millette

Ashley Millette

Ashley is a Specialist Solutions Architect for Streaming and Analytics at AWS. She partners with customers to design and implement real-time data streaming architectures using services like Amazon MSK, helping them build scalable, cost-effective pipelines that turn data in motion into actionable insights. She is passionate about simplifying complex streaming workloads and enabling customers to modernize their data infrastructure with confidence.

Amazon MSK Service 101: How many partitions does an Amazon MSK topic need?

Post Syndicated from Yashika Jain original https://aws.amazon.com/blogs/big-data/amazon-msk-service-101-how-many-partitions-does-an-amazon-msk-topic-need/

Customers new to Amazon Managed Streaming for Apache Kafka (Amazon MSK) often ask how many partitions their topics need. Choosing the right partition count is one of the most impactful architectural decisions you make, because it directly affects throughput, scalability, and operational complexity.

In Apache Kafka, a topic is the fundamental unit for categorizing data streams, but to achieve high scalability and performance, Kafka divides topics into smaller, independent units called partitions.

In this post, we provide practical guidance for determining the ideal partition count for your use case.

Understanding Kafka partitions

In
Apache Kafka, a partition is the unit of storage and parallelism. Each partition is an ordered, immutable log that can store records as they are produced to a topic. When you create a topic, Kafka distributes its partitions across the brokers in the cluster. Partitions allow Kafka to scale in three key ways:
  • Parallelism – Within a consumer group, each partition can be read by only one consumer at a time. Each partition maps to a dedicated log file in storage on the broker, and Kafka manages these logs through separate processing threads. This architecture allows more partitions to support more consumers processing data in parallel, with each partition’s log being independently managed for read and write operations.
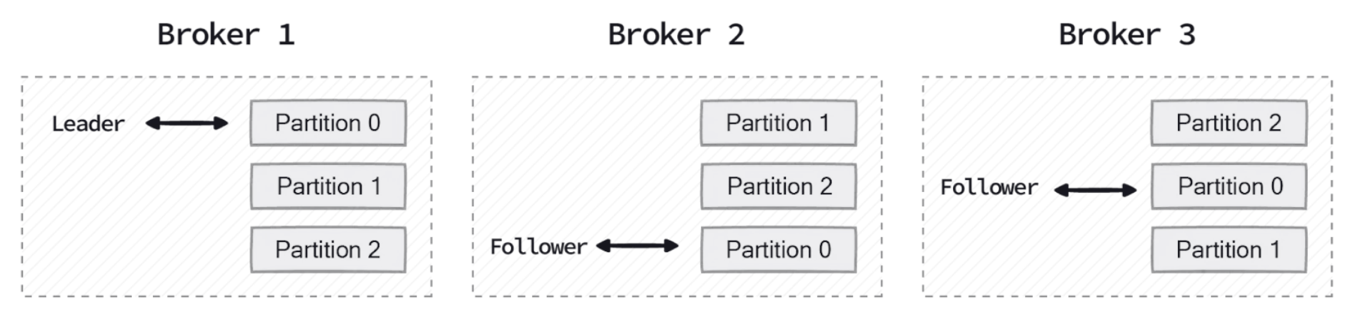
The following diagram shows how Kafka distributes partition replicas across a three-broker cluster, with each broker serving as a leader for some partitions and a follower for others.
Partitions 0, 1, and 2 replicated across three brokers, each a leader for some partitions and a follower for others

Figure 1: Partition replicas distributed across a three-broker cluster

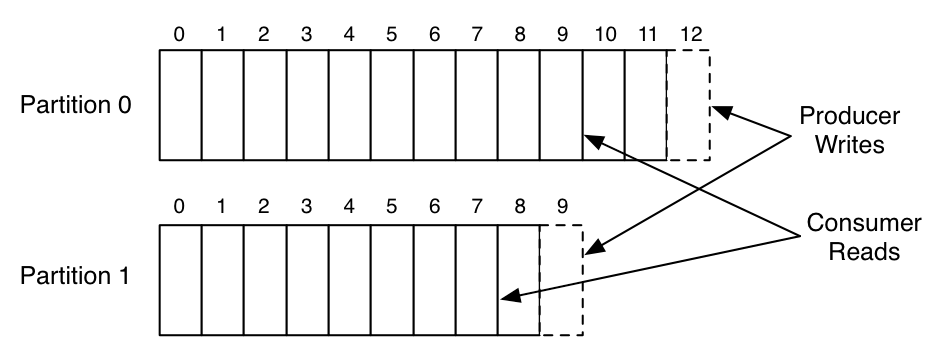
The following diagram illustrates how producers append new records to the end of a partition log, while consumers read sequentially from their current offset position.

Producers append records to the tail of partition logs while consumers read sequentially from their offset position

Figure 2: Producer writes and consumer offset positions in two partition logs

  • Throughput – Producers and consumers can read and write data in parallel across partitions, increasing overall throughput.
  • Scalability – Partitions allow Kafka to spread data and load across multiple brokers instead of concentrating it on a single node.

However, increasing partitions comes with trade-offs. Each partition adds metadata overhead, consumes memory, and requires file handles on the broker. While more partitions improve throughput and parallelism, they also increase the operational burden on the cluster. Too many partitions can lead to longer leader election times during broker failures, increased end-to-end latency, and higher memory consumption for both producers and consumers managing connections to multiple partitions.

Trade-offs when choosing partition count

Choosing a partition count is a balancing act between parallelism and resource utilization.

Benefits of more partitions

Using more partitions can significantly improve throughput by allowing Kafka to distribute read and write traffic across more brokers. This is particularly useful for high-volume ingestion pipelines and real-time analytics workloads. More partitions also allow consumer groups to scale horizontally, because the maximum number of active consumers in a group is limited by the number of partitions. In addition, choosing a partition count that is evenly divisible by the number of brokers helps provide balanced leadership and replica distribution, reducing the risk of uneven load.

Operational costs of more partitions

However, higher partition counts also come with costs. When a broker fails or undergoes maintenance, Kafka must perform recovery operations for each affected partition. During recovery, Kafka elects new leaders for partitions that were hosted on the unavailable broker and replicates data from the remaining in-sync replicas to newly assigned brokers. This process involves copying partition data across the network to restore the replication factor, which can be resource intensive. As the number of partitions increases, these recovery operations take longer because each partition requires its own leader election and data replication cycle.

You might encounter clusters with very high partition counts that experience extended recovery times during rolling upgrades, even when overall traffic volumes are modest. Amazon MSK Express brokers address this challenge by recovering 90x faster and providing 180x faster elasticity when scaling out clusters. This significantly reduces the operational impact of high partition counts during maintenance windows and failure scenarios.

Infrastructure cost implications

Beyond operational complexity, more partitions can directly increase infrastructure costs. Amazon MSK publishes partition-per-broker limits that vary by instance type. When the total partition count (including replicas) exceeds what the current broker fleet can support, you must add brokers to stay within recommended limits, even if throughput alone does not warrant the additional capacity.

Amazon MSK partition-per-broker guidelines

Amazon MSK publishes recommended partition-per-broker guidelines to help you operate clusters reliably. These values are strict limits. Exceeding them can lead to operational challenges, particularly during broker replacement or rolling upgrades, and can block cluster operations such as configuration updates or scaling down.

Express brokers support up to 5x more partitions per broker compared to Standard brokers. For example, the largest Standard broker (kafka.m7g.16xlarge) supports a recommended maximum of 4,000 partitions per broker. The equivalent Express broker (express.m7g.16xlarge) supports up to 20,000 recommended partitions per broker. This higher partition density means partition-bound workloads can be hosted on fewer brokers, improving price-performance by up to 50% for such workloads.

We recommend setting Amazon CloudWatch alarms on PartitionCount per-broker metrics to proactively monitor your partition distribution. When an alarm triggers, evaluate your partition strategy and consider rebalancing partitions across brokers, consolidating topics, or scaling out your cluster to stay within recommended limits. For detailed guidance, see Right-size your cluster: Number of partitions per Standard broker and Express broker partition quota.

Practical guidance for choosing a partition count

There is no single formula that works for every Kafka workload. In practice, you typically combine several considerations when sizing partitions.

  • Start with throughput requirements – The first step is to determine your per-partition throughput capacity, which then informs how many partitions you need.

For Express brokers, use the per-broker throughput capacity as the primary means for sizing your cluster. Express brokers feature a fully managed storage layer, so you do not need to separately account for storage I/O constraints. The published per-broker limits represent the effective capacity available to your workload.

For Standard brokers, the achievable throughput depends on additional factors beyond the broker instance size. These factors include provisioned EBS storage throughput, the number of consumer groups reading from the broker, and how much data is served from memory versus disk. Storage I/O is consumed when producers write, when data replicates between brokers, and when consumers read data that is not in memory. For this reason, validate the effective per-partition throughput for Standard brokers through load testing in your environment.

Once you know your per-partition throughput, calculate the required number of partitions: Number of partitions = Peak throughput of the topic ÷ Throughput per partition

For example, if a topic must handle 40 MB/sec at peak and your testing shows each partition can sustain 5 MB/sec, you would need: 40 ÷ 5 = 8 partitions. Always validate these assumptions with load testing, as actual throughput varies based on your workload characteristics. For initial sizing estimates, refer to the Amazon MSK Sizing and Pricing worksheet and the Amazon MSK Best Practices documentation.

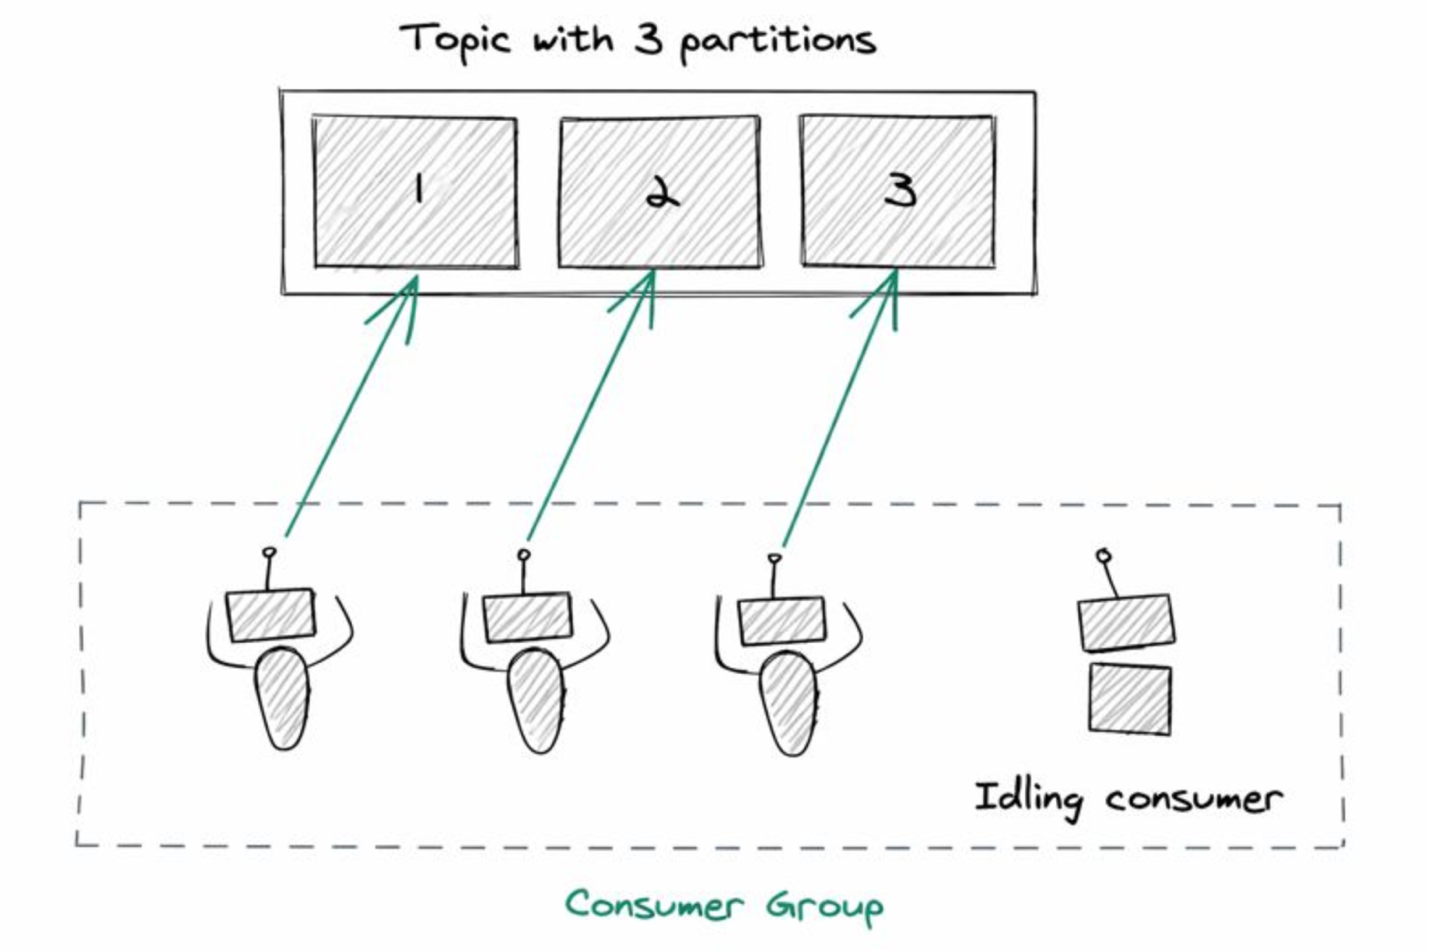
  • Consider your consumer parallelism needs – If you know the number of consumers required during peak processing times, use that as your partition count. We don’t recommend having more active consumers in a consumer group than partitions. For example, if you have 5 partitions, only 5 consumers can actively process data. Additional consumers remain idle. These idle consumers still maintain active TCP connections to the brokers, sending frequent heartbeats and group coordination requests. This might result in unnecessary overhead on broker resources and contribute to high CPU usage despite low egress traffic.
Consumer group with more consumers than partitions, leaving the extra consumers idle

Figure 3: Idle consumers when a consumer group has more consumers than partitions

  • Producer throughput and partition keys – When sizing partitions, consider producer-side throughput in addition to consumer parallelism. If producers generate data faster than a single partition can handle, additional partitions can help distribute write traffic across brokers. Partition keys also play a critical role. Poorly distributed or low-cardinality keys can create hot partitions and limit throughput. In such cases, increasing the number of partitions alone does not improve throughput unless records are evenly distributed.
  • Plan for even distribution and future growth – Kafka works best when partitions can be spread evenly across brokers. Instead of focusing on specific numbers, aim for partition counts that divide reasonably well across your expected broker count. This reduces reassignment churn when brokers are added or replaced. But avoid excessive over-partitioning. It’s reasonable to leave some headroom for future growth. However, creating thousands of partitions “just in case” often causes more harm than good. Increasing partitions later is supported, but it can affect ordering guarantees and may require consumer changes. Start with a conservative number, monitor real traffic patterns, and scale gradually.

From an operational perspective, Amazon MSK provides recommended partition-per-broker guidelines based on broker instance type. Exceeding these guidelines increases operational risk and can block cluster operations such as version upgrades, scaling, or configuration changes. Large partition counts can also increase consumer group rebalance duration, temporarily pausing message processing and increasing end-to-end latency.

Keep in mind that partitioning improves scalability, but it does not address application-level bottlenecks such as slow consumers, inefficient processing logic, or downstream system constraints.

Conclusion

Determining the right number of partitions for an Amazon MSK topic is a foundational design decision. It affects throughput, scalability, failure recovery, and day-to-day operability of your Kafka cluster. Start by understanding your throughput and consumer parallelism needs, respect Amazon MSK partition-per-broker guidelines, avoid excessive over-partitioning, and validate assumptions through load testing. Most importantly, there is no universal “correct” number, only a number that fits your workload, operational goals, and cost.

For more information, see the Amazon MSK Developer Guide and Recommended best practices for Amazon MSK.


About the authors

Yashika Jain

Yashika Jain

Yashika is a Senior Cloud Analytics Engineer at AWS, specializing in real-time analytics and event-driven architectures. She is committed to helping customers by providing deep technical guidance, driving best practices across real-time data platforms and solving complex issues related to their streaming data architectures.

Ali Alemi

Ali Alemi

Ali is a Principal Streaming Solutions Architect at AWS. Ali advises AWS customers with architectural best practices and helps them design real-time analytics data systems which are reliable, secure, efficient, and cost-effective. Prior to joining AWS, Ali supported several public sector customers and AWS consulting partners in their application modernization journey and migration to the Cloud.

Amazon MSK simplifies configuring custom domain names

Post Syndicated from Ali Alemi original https://aws.amazon.com/blogs/big-data/amazon-msk-simplifies-configuring-custom-domain-names/

Previously, you had to manually override the advertised listener on each broker and repeat it every time a broker was added. This approach was operationally heavy and could not be implemented on a cluster in KRaft mode. With Amazon Managed Streaming for Apache Kafka (Amazon MSK), you can now configure custom domain names for your Provisioned clusters using a single property. This works for clusters in both ZooKeeper and KRaft mode. Now you define the domain once and Amazon MSK applies it across every broker, so custom domain names keep working through scaling of the MSK cluster.

Custom domain names on Amazon MSK

Amazon MSK is a fully managed service for building and running applications that use Apache Kafka to process streaming data. By default, Amazon MSK brokers advertise addresses that AWS generates (for example, b-1.cluster-name.kafka.us-east-1.amazonaws.com) to connecting clients. These addresses are unique to each cluster and change when a cluster is recreated.

Many organizations need a static, customer-controlled endpoint that stays the same regardless of the underlying cluster. They achieve this with a custom domain name, so that they can:

  • Route traffic through Network Load Balancers (NLBs) when IP exhaustion forces clusters into non-routable subnets.
  • Avoid client reconfiguration during cluster migrations, so clients keep the same endpoint even when the underlying cluster changes.
  • Simplify disaster recovery (DR) failover, where the same domain fronts both primary and standby clusters.
  • Align with organizational naming, security, and compliance conventions.

Until now, the only way to do this was to override the advertised.listeners on each broker using the kafka-configs.sh --alter tool. It required carefully preserving every internal listener and re-running that override every time a broker was added. This works, but it accepts any string with no validation. A single typo can cause an outage. It requires manual, per-broker steps with no cluster-wide mechanism. It cannot be managed through infrastructure as code, and it could not be implemented on Amazon MSK brokers in KRaft mode. This blocked customers who rely on custom domain names from using them on KRaft-based clusters. With this launch, a single configuration property replaces all of that.

What you set up, and what Amazon MSK manages

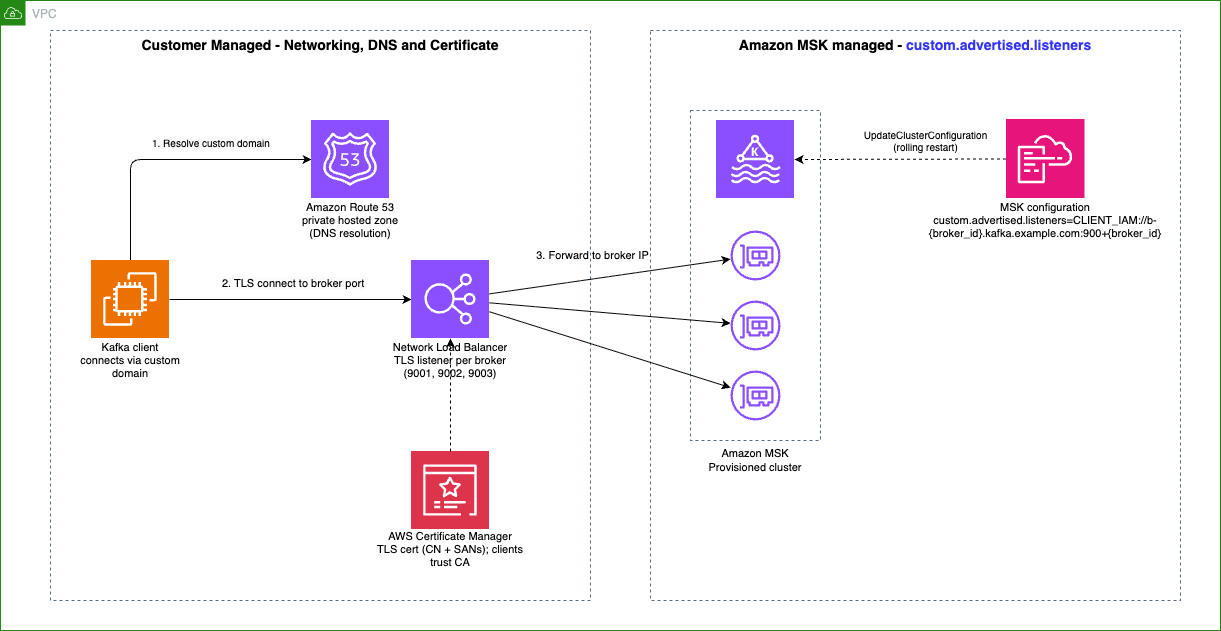
A working custom domain name has two parts, and understanding this split up front helps the rest of this post make sense. You own the client connectivity and trust layer. Amazon MSK owns the cluster-side advertised listener configuration. The following diagram shows the client connectivity and trust layer.

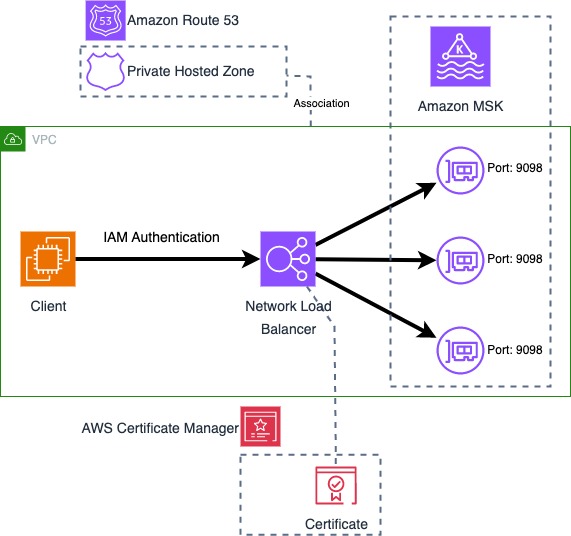
Diagram of the client connectivity and trust layer you manage and the advertised listener configuration Amazon MSK manages

Figure 1: The client connectivity and trust layer (left) is a prerequisite you own and manage. The advertised listener configuration on the cluster (right) is what Amazon MSK manages for you

Important: When you apply custom.advertised.listeners, your custom domain name replaces the default addresses that clients use to connect to broker nodes. If the networking and trust layer is not already in place, resolvable, reachable, and trusted from the client, the client cannot reconnect, even though it was connected moments earlier.

Part 1: The client connectivity and trust layer (you manage)

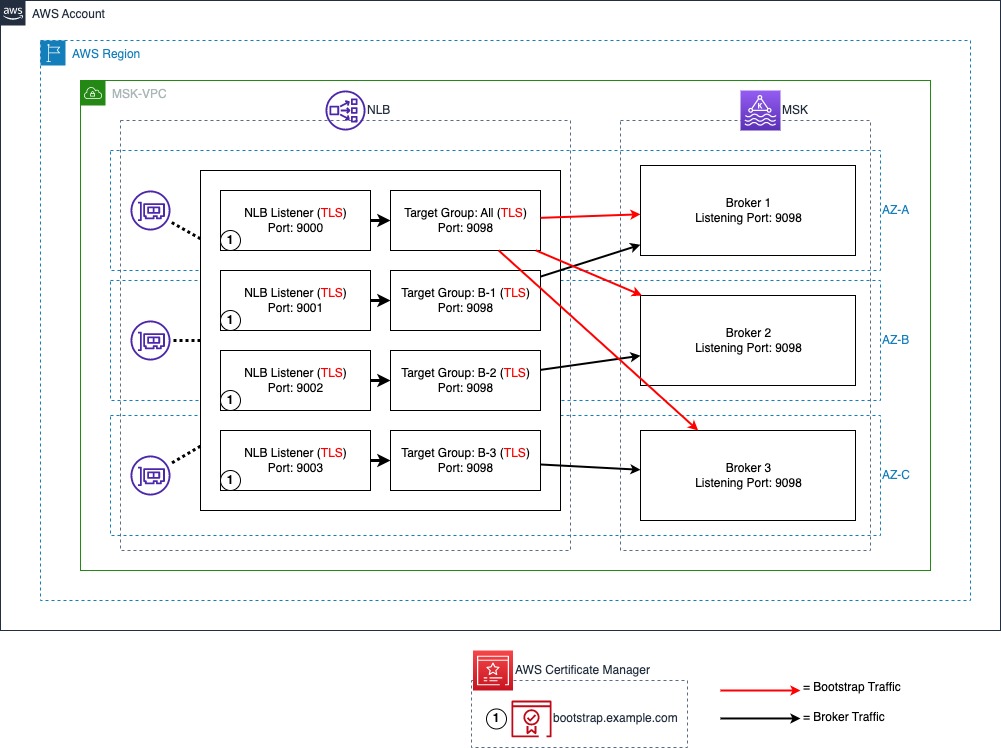
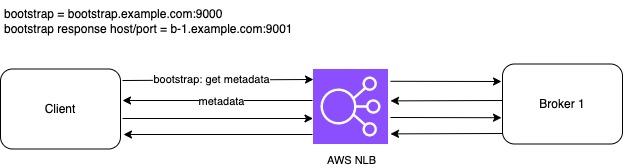
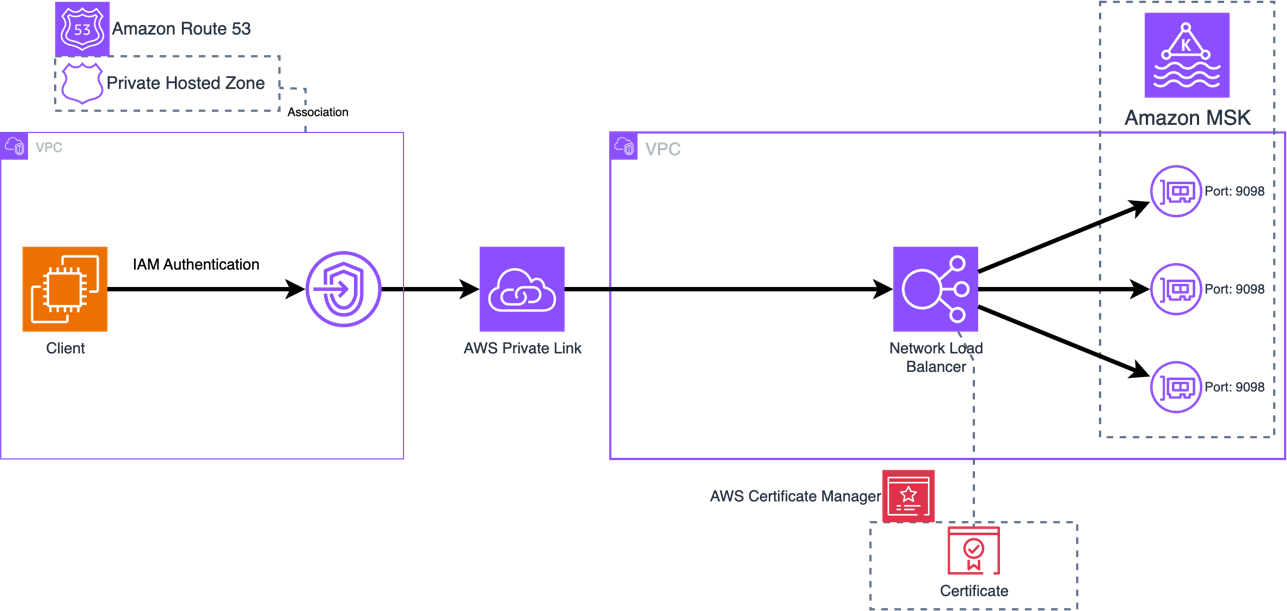
The Prerequisites section below shows the key requirements. You can find the detailed setup in an existing post, Configure a custom domain name for your Amazon MSK cluster, which includes a diagrammed walkthrough of the NLB, Amazon Route 53, and AWS Certificate Manager (ACM) topology.

Part 2: The advertised listener configuration (Amazon MSK managed)

After the connectivity layer exists, you tell the brokers which custom address to advertise to clients. This is the part that used to require a per-broker CLI override, and it is what this launch simplifies. This next section describes how it works.

Prerequisites

Before a client can reach your brokers through a custom domain, the connectivity and trust path must exist. You create and manage this layer. It covers three things:

  • Networking: A network gateway, like a Network Load Balancer (NLB), TLS certificate, DNS records, and security groups that route traffic from your custom domain to your broker IPs.
  • Certificate trust: The client’s truststore must include certificate authorities in the path (the load balancer’s custom-domain cert).
  • DNS resolution: Clients must resolve the custom domain to your NLB, typically through an Amazon Route 53 private hosted zone associated with the client virtual private cloud (VPC).

This layer must be in place for custom domain names to function. It is a prerequisite for this feature to work.

How it works

You add a property to your Amazon MSK configuration. The value takes the form:

custom.advertised.listeners=<LISTENER>://<hostname>:<port>

where <LISTENER> is one of your cluster’s client listeners and <hostname>:<port> is the custom address pattern. For example, on an IAM cluster:

custom.advertised.listeners=CLIENT_IAM://b-{broker_id}.example.com:9000+{broker_id}

The property specifies two things:

  1. Each listener corresponds to an authentication type on your cluster. Custom advertised endpoints can be set only for client listeners: CLIENT, CLIENT_SECURE, CLIENT_SECURE_PUBLIC, CLIENT_SASL_SCRAM, CLIENT_SASL_SCRAM_PUBLIC, CLIENT_IAM, and CLIENT_IAM_PUBLIC. Internal listeners (REPLICATION, CONTROLLER) are not supported and are rejected at validation. The listener you specify must also be bound (active) on your cluster. For example, if your cluster uses only IAM authentication, specifying CLIENT_SECURE is rejected, and the error message lists the valid client listeners for your cluster.
  2. A custom hostname:port pattern that includes the {broker_id} template variable. Each broker resolves to a unique address. In this pattern, the {broker_id} template variable is replaced with each broker’s numeric ID. The port number 9000+{broker_id} means the broker ID is added to the base port 9000, so broker 1 resolves to 9001, broker 2 to 9002, broker 10 to 9010, and so on. The base port 9000 is only an example. You can use any base port, as long as the resulting ports match the TLS listeners you provisioned on your NLB.

{broker_id} can appear in the hostname, the port, or both, as long as each broker’s resolved host:port is unique. Placing it in the port alone is valid, so a shared hostname with a per-broker port also works:

custom.advertised.listeners=CLIENT_IAM://example.com:9000+{broker_id}

Before you begin, you need an MSK configuration to hold this property. You create one with the CreateConfiguration API (or the AWS Management Console), passing your server properties as the configuration body. MSK returns a configuration ARN and a revision number, which together identify the exact configuration you apply to the cluster.

custom.advertised.listeners does not need its own standalone configuration. You can include it alongside any other broker-level properties MSK already supports, such as auto.create.topics.enable, num.partitions, or log-retention settings, within a single configuration revision. If you already manage an MSK configuration for your cluster, add custom.advertised.listeners to it and create a new revision using the UpdateConfiguration API. No separate configuration is needed.

You then apply the configuration to your cluster with the UpdateClusterConfiguration API. Amazon MSK then performs three actions:

  • Validates the configuration.
  • Resolves the pattern for each broker.
  • Applies it through a rolling restart across the cluster.

These safeguards prevent you from accidentally removing or modifying the internal listeners that Amazon MSK manages. Validation is synchronous. The listener must be a client-facing listener, the pattern must include {broker_id}, and each broker’s resolved host:port must be unique. If any check fails, the API returns a descriptive error and makes no change.

The override affects only the advertised address of the named listener. Replication, authentication, multi-VPC (CLIENT_IAM_VPCE), and AWS PrivateLink connectivity remain unaffected. The change is also fully reversible: remove the custom.advertised.listeners property and re-apply the configuration, and Amazon MSK reverts the listener to its original address.

You can track progress with the DescribeOperation API, which shows state transitions from UPDATE_IN_PROGRESS to UPDATE_COMPLETE or UPDATE_FAILED. If a broker fails to start, the rollout halts at that broker, the remaining brokers keep their previous configuration, and you can fix the property and re-apply to recover.

Setting up a custom domain name end to end

When you apply custom.advertised.listeners, your custom domain name replaces the default addresses that clients use to connect to broker nodes. If the networking and trust layer is not already in place, resolvable, reachable, and trusted from the client, the client cannot reconnect, even though it was connected moments earlier.

The networking layer, the Network Load Balancer (NLB), DNS, and TLS certificate that route traffic from your custom domain to your broker IPs, is a prerequisite you own. It is not specific to this launch. The existing post Configure a custom domain name for your Amazon MSK cluster covers it in detail, with a diagrammed walkthrough of the NLB, Route 53, and ACM topology. With the networking in place, the following steps cover the cluster-side setup this launch introduces.

Step 1: Add the custom domain to your Amazon MSK configuration

Create or update an Amazon MSK configuration that includes the custom.advertised.listeners property, matching the hostnames and ports you provisioned on the NLB. For a three-broker IAM cluster fronted by an NLB with ports 9001–9003, put the property in a file:

custom.advertised.listeners=CLIENT_IAM://b-{broker_id}.example.com:9000+{broker_id}

Then create the configuration, passing the file as the server properties:

aws kafka create-configuration \
    --name "custom-domain-iam" \
    --description "Custom advertised listeners for CLIENT_IAM" \
    --server-properties fileb://custom-domain-config.txt

Use fileb:// (not file://) so the CLI reads the file as bytes and base64-encodes it. Passing the value inline is fragile because of the {broker_id} braces. Leave {broker_id} literal in the file. Amazon MSK resolves it per broker at apply time. The response returns the configuration ARN and LatestRevision.Revision, which you use in the next step.

Step 2: Apply the configuration

Apply the configuration to your cluster with UpdateClusterConfiguration, using the console, AWS Command Line Interface (AWS CLI), AWS CloudFormation, CDK, or Terraform. This is the same workflow you already use for broker configuration changes.

aws kafka update-cluster-configuration \
    --cluster-arn <your-cluster-arn> \
    --configuration-info arn=<configuration-arn>,revision=<revision> \
    --current-version <current-cluster-version>

If the configuration fails to apply, review the errors. For details, see the troubleshooting section in the Amazon MSK Developer Guide.

Step 3: Track the rollout

aws kafka describe-cluster-operation-v2 \
    --cluster-operation-arn <operation-arn>

After the configuration is accepted, Amazon MSK applies it through a rolling restart. Wait until the operation reports SUCCESS. If it reports FAILED, a broker could not apply the change. The rollout halts at that broker, the remaining brokers keep their previous configuration, and you can fix the configuration and re-apply to recover.

Step 4: Verify

Confirm clients can connect through the custom domain:

kafka-topics.sh --list --bootstrap-server b-1.example.com:9001

If your topic list is returned, clients are successfully connecting through your custom domain. If the operation reported SUCCESS but clients cannot connect, the cluster-side configuration is correct, but your networking layer likely needs attention.

Client connectivity during rollout

This step is important. Clients can be disconnected if the networking is not ready. Kafka clients do not keep using the original address they bootstrapped with. On a periodic metadata refresh, each client learns the broker’s advertised listener. The client uses that address for all subsequent connections. When you apply a custom domain name, that advertised address changes from the default name that Amazon MSK generates to your custom domain, so at the next metadata refresh every client connects over the custom domain. For this reason, the connectivity and trust layer described in What you set up, and what Amazon MSK manages is a prerequisite, not a follow-up task.

The safe sequence, which is also how customers move from Amazon DNS to a custom domain today, is two phases:

  1. Build the networking path first: Stand up the NLB, DNS, and certificate, and point your clients at the custom bootstrap endpoint, but do not set the advertised listener yet. Clients bootstrap through the custom endpoint while still connecting to brokers over the addresses that Amazon MSK generates.
  2. Configure the advertised listener: With the path already in place, applying custom.advertised.listeners changes what the brokers advertise. At the next metadata refresh, clients pick up the custom domain and cut over to it automatically.

Because the path already exists, this cutover is transparent: as Amazon MSK applies the change broker by broker, clients reconnect on their own, with no restart or reconfiguration.

Scaling and replacement of brokers

When you scale the cluster or a broker is replaced during automated healing, Amazon MSK automatically applies the configuration to the new broker, resolving {broker_id} for its ID, with no manual steps required on the cluster side. Remember to add the corresponding NLB listener, target group, and DNS record for any new broker, because the networking layer does not auto-scale.

Conclusion

Custom domain name configuration turns a per-broker CLI workaround into a single, validated, cluster-wide Amazon MSK configuration property. It works identically on ZooKeeper and KRaft, persists through scaling and failover, and flows through your existing Terraform, CloudFormation, and CLI workflows. If you rely on custom domain names, we recommend adopting the static configuration now.

This capability is available on all Amazon MSK Provisioned clusters with Standard and Express brokers, in all AWS Regions where Amazon MSK Provisioned is available. To get started, see the Amazon MSK Developer Guide and the end-to-end networking walkthrough in Configure a custom domain name for your Amazon MSK cluster.


About the authors

Ali Alemi

Ali Alemi

Ali is a Streaming Specialist Solutions Architect at AWS. Ali advises AWS customers with architectural best practices and helps them design real-time analytics data systems. Prior to joining AWS, Ali supported several public sector customers and AWS consulting partners in their application modernization journey and migration to the cloud.

Subham Rakshit

Subham Rakshit

Subham is a Streaming Specialist Solutions Architect for Analytics at AWS based in the UK. He works with customers to design and build search and streaming data platforms that help them achieve their business objective. Outside of work, he enjoys spending time solving jigsaw puzzles with his daughter.

NaranjaX manages multiple Amazon MSK Serverless clusters in different accounts from their IDP using AWS RAM and Route 53

Post Syndicated from Federico Ostrit original https://aws.amazon.com/blogs/big-data/naranjax-manages-multiple-amazon-msk-serverless-clusters-in-different-accounts-from-their-idp-using-aws-ram-and-route-53/

NaranjaX is a leading fintech platform that aims to simplify and improve the daily financial lives of millions of people in Argentina. Through its digital ecosystem, NaranjaX offers a complete suite of financial products and services, including payments, collections, financing, savings, and protection products.

NaranjaX needed to evolve from their REST-based architecture to an event-driven architecture using Amazon Managed Streaming for Apache Kafka (Amazon MSK) Serverless. In a multi-account environment, MSK Serverless clusters resolve DNS names within their hosting account. AWS published a cross-account connectivity pattern that centralizes clusters in a single account. This is an effective approach for many organizations. NaranjaX required additional flexibility to distribute clusters across accounts while avoiding centralized quota dependencies.

NaranjaX addressed this requirement by developing an approach that uses AWS Resource Access Manager (AWS RAM) and Amazon Route 53 Resolver. In this post, we show you how to expand Amazon MSK Serverless adoption across multiple accounts while maintaining scalability, availability, and reduced operational overhead.

Solution overview

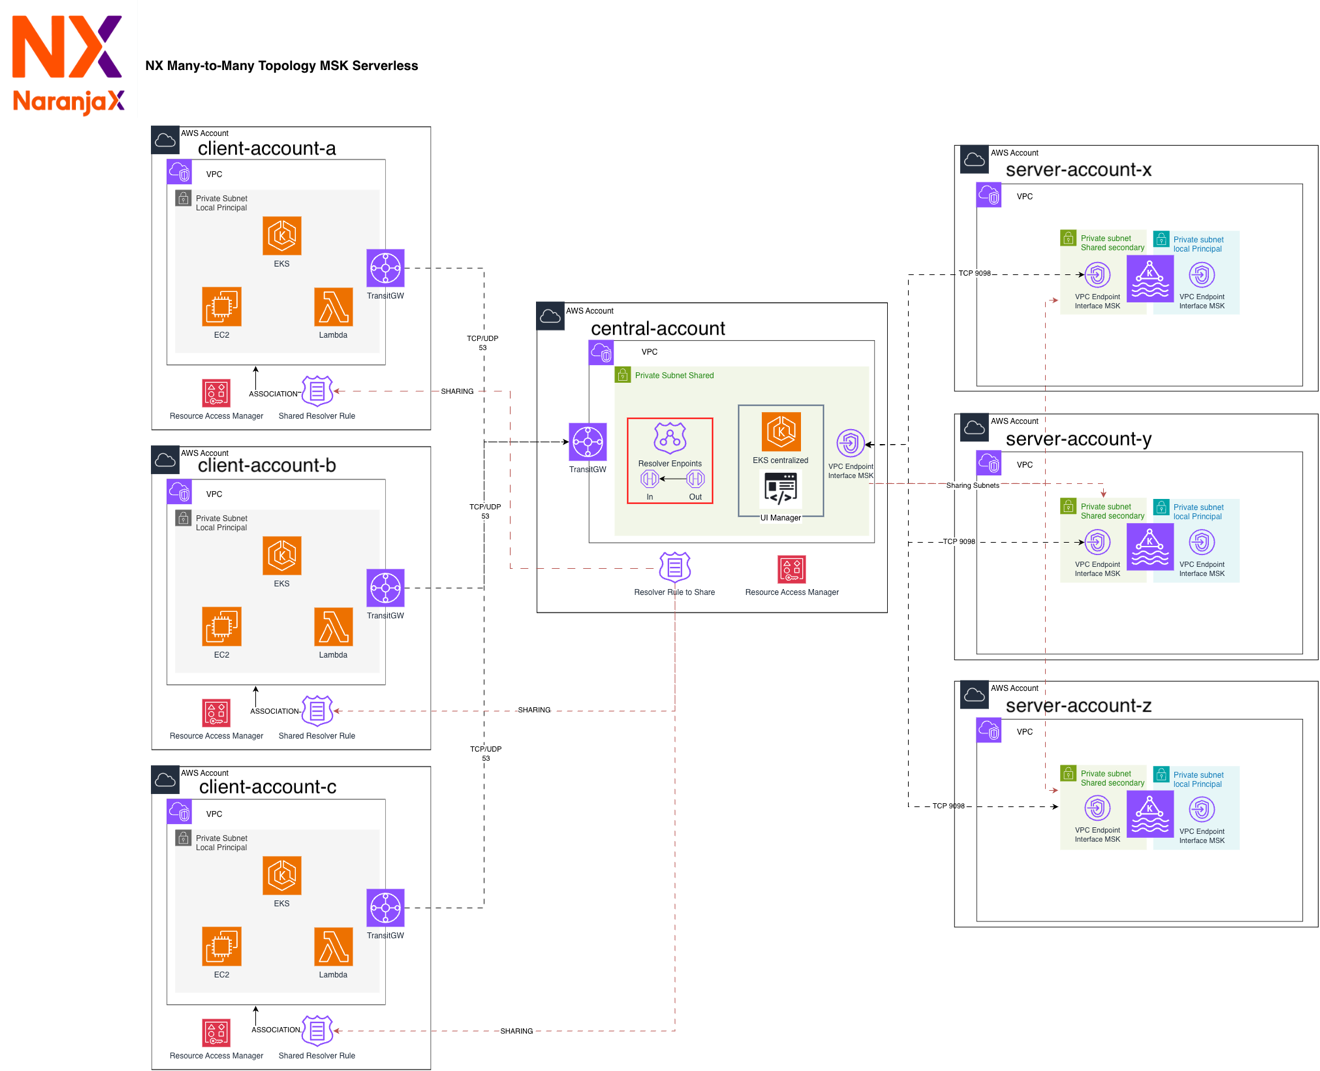
NaranjaX’s solution supports cross-account MSK Serverless deployment through a centralized networking architecture that combines shared virtual private cloud (VPC) resources and DNS resolution capabilities. The solution uses a central AWS account that hosts shared private subnets and Route 53 resolver endpoints, so that MSK Serverless clusters in different accounts can communicate across account boundaries.

The architecture consists of three main components:

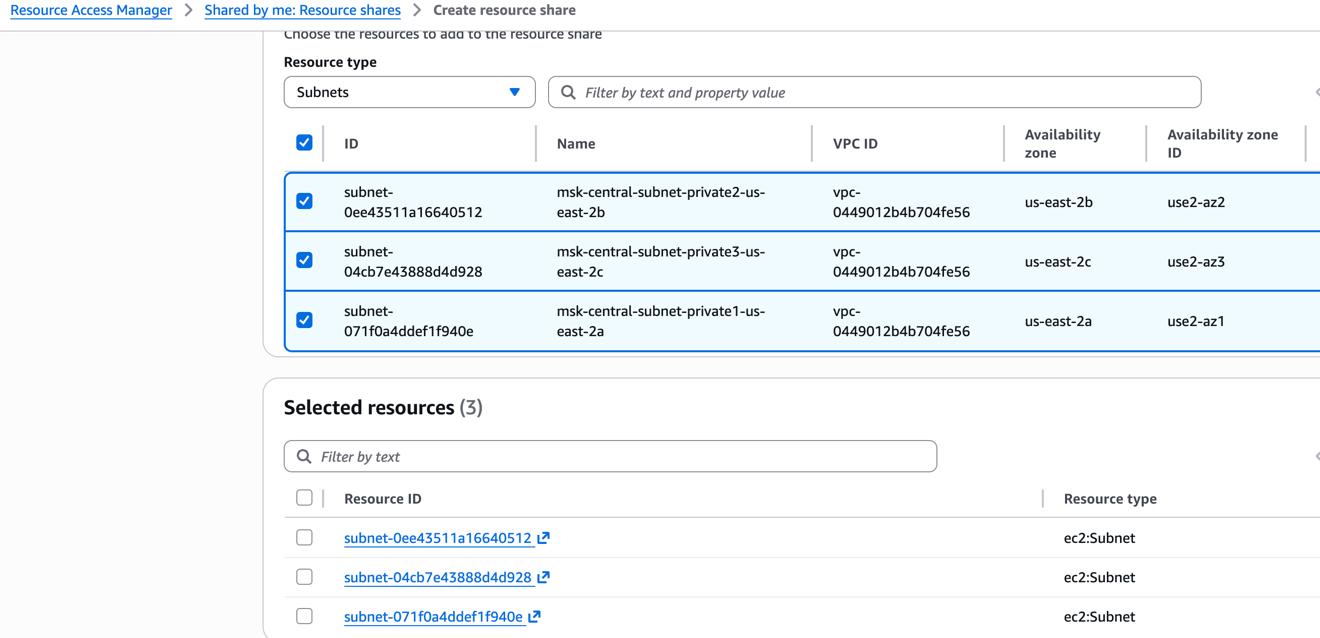
  1. A central VPC with private subnets that are shared across accounts using AWS RAM.
  2. Route 53 resolver endpoints and rules that resolve DNS across accounts for MSK Serverless clusters.
  3. Network security configurations that control communication between components.

When an application team creates an MSK Serverless cluster in their account, they can associate it with the shared VPC subnets. The Route 53 resolver rules handle DNS resolution for the cluster’s domain names, while security groups manage access control. This design supports direct connectivity between MSK Serverless clusters and applications across different AWS accounts.

Architecture diagram showing a central account that shares VPC subnets and Route 53 resolver endpoints with application accounts running MSK Serverless clusters

Figure 1: Cross-account architecture with a central networking account sharing subnets and Route 53 resolver endpoints

Implementation requirements and configuration

This section walks you through the steps to configure cross-account MSK Serverless connectivity using shared VPC subnets and Route 53 resolver rules. Before you begin, make sure you have the prerequisites in place.

Prerequisites

Before implementing this solution, confirm the following:

  1. AWS RAM is enabled in your AWS Organization. For instructions, see Enabling resource sharing within AWS Organizations.
  2. Amazon MSK supports shared subnets. When you create an MSK Serverless cluster in any account, you can associate the shared VPC as one of the up to five VPCs supported by the service.
  3. You have a multi-account environment with at least one central networking account and one or more application accounts.
  4. You have permissions to create VPCs, subnets, Route 53 resolver endpoints, and AWS RAM resource shares in the central account.

Step 1: Share subnets with AWS RAM in a central account

First, create a VPC with private subnets in your central networking account. These subnets are the resources you will share through AWS RAM. For details, see Creating a VPC in the Amazon VPC User Guide.

Next, create a resource share for those subnets in AWS RAM. Select the subnets you created and specify the target accounts.

Finally, specify the principals (account IDs) authorized to use the shared subnets. These are the accounts where you will create your Amazon MSK Serverless clusters.

AWS RAM console creating a resource share and selecting the private subnets to share

Figure 2: Creating a resource share for the private subnets in AWS RAM

AWS RAM console specifying the target accounts for the shared subnets

Figure 3: Specifying the target accounts for the resource share

AWS RAM console confirming the principals authorized to use the shared subnets

Figure 4: Confirming the principals authorized to use the shared subnets

Step 2: Configure Amazon Route 53 Resolver rules

In your central account, create a Route 53 Resolver rule for the domain *.kafka-serverless.<Region>.amazonaws.com. Don’t associate this rule with any VPC at this point.

Amazon Route 53 Resolver rule for the kafka-serverless domain created in the central account

Figure 5: Route 53 Resolver rule for the kafka-serverless domain

Configure this as a forward rule for the kafka-serverless subdomain. Set up an outbound endpoint in the central account and point the target IP addresses to the inbound endpoint in the same account.

Route 53 Resolver forward rule configuration with an outbound endpoint pointing to the inbound endpoint

Figure 6: Forward rule configuration with outbound and inbound resolver endpoints

Share the resolver rule with your application accounts using AWS RAM so they can resolve the DNS names of their MSK Serverless clusters.

Make sure the central VPC has both inbound and outbound resolver endpoints configured to support cross-account DNS resolution.

Step 3: Configure network security groups

Configure security groups in each consuming account to allow inbound and outbound traffic on port 53 (DNS resolution) and port 9098 (Kafka IAM authentication). This supports both name resolution and secure connectivity to your MSK Serverless brokers across account boundaries.

Step 4: Enable and test many-to-many connectivity

With the networking infrastructure in place, you can now create MSK Serverless clusters in any of your application accounts. To do this, create an MSK Serverless cluster in your application account and associate it with the shared VPC subnets from the central account. The Route 53 resolver rules automatically handle DNS resolution for the cluster endpoints, and the security groups you configured control access. This eliminates the restriction of hosting all clusters in a single account.

You have flexibility in how you configure DNS resolution for your clients. For example, in a client account, you can associate the shared resolver rule with a VPC directly, or you can use the inbound endpoint IP addresses from the central account as custom DNS servers. Configure these either in per-connection scripts or in DHCP option sets for a separate VPC.

To verify connectivity, use the dig command from an instance in a client account VPC to test DNS resolution of MSK Serverless bootstrap strings across different accounts. The following example uses the +short flag for clarity:

Terminal output of the dig command resolving two MSK Serverless bootstrap strings to broker IP addresses across accounts

Figure 7: The dig command resolving MSK Serverless bootstrap strings across accounts

The output shows that two MSK Serverless clusters (bootstrap strings starting with boot-*) in different accounts and VPCs resolve to the actual IP addresses of the three brokers listening for connections.

This confirms that the architecture supports scalable, consistent cross-account communication for event-driven workloads.

Key benefits

NaranjaX’s implementation of MSK Serverless as its integration backbone delivered measurable advantages across 15+ application teams and over 40 AWS accounts, transforming application development and operations.

Scalability with optimized cost

With MSK Serverless, teams can scale workloads automatically without managing broker capacity. Combined with AWS RAM and Route 53, the architecture supports growth across over 40 accounts while maintaining cost efficiency. By removing the need for dedicated Kafka operations staff and self-managed clusters, NaranjaX reduced infrastructure management costs by approximately 40 percent compared to their previous self-managed Kafka deployment.

Simplified governance and security

Centralized DNS management and VPC sharing keep configurations standardized across all accounts. IAM-based access control, integrated with KATHU, provides clear visibility into topic ownership and consumer access, reducing security review cycles from days to hours.

Faster developer onboarding through IDP integration

By integrating Kafka control-plane operations directly into their internal developer platform (IDP), teams can provision clusters and topics through Terraform modules or a graphical interface. This reduced onboarding time for new teams adopting event-driven architecture from weeks to less than one day.

Reduced operational overhead

Application teams can focus on delivering business features rather than managing Kafka infrastructure. Central operations handle DNS, networking, and resource sharing, while MSK Serverless abstracts broker administration. This reduced operational tickets related to Kafka by over 70 percent and freed the platform team to focus on higher-value initiatives.

Next steps

NaranjaX is evaluating extending this solution by incorporating automatic topic replication across accounts using MSK Replicator, so that certain topics can be exposed as Enterprise Topics in a central hub for global consumption. This will further simplify the architecture, improve data resiliency, and enhance visibility across event domains.

Conclusion

Through this architecture, NaranjaX successfully implemented a many-to-many connectivity model for Amazon MSK Serverless across more than 20 AWS accounts. By using AWS RAM and Amazon Route 53 Resolver, the organization achieved a scalable, secure, and centralized network topology that accelerates the adoption of event-driven architecture without operational bottlenecks. This approach complements the cross-account connectivity pattern published by Tamer Soliman, and provides additional flexibility for organizations that require distributed Kafka clusters in large-scale multi-account environments. To get started, see the Amazon MSK documentation and try this approach in your own multi-account environment.


About the authors

Federico Ostrit

Federico Ostrit

Federico is a Staff Engineer at NaranjaX, where he designs and evolves cloud-native platforms on AWS. He specializes in event-driven architectures, Kubernetes, and distributed systems, helping engineering teams build scalable, resilient, and secure solutions.

Hernan Antolini

Hernan Antolini

Hernan is a Senior Solutions Architect at AWS. He works with FSI customers like NaranjaX in the design of solutions in AWS. He has almost 30 years of experience in IT infrastructure and more than 6 years working in AWS.

How AppFolio transformed its data streaming architecture with Amazon MSK Express brokers

Post Syndicated from Brandon Stanley original https://aws.amazon.com/blogs/big-data/how-appfolio-transformed-its-data-streaming-architecture-with-amazon-msk-express-brokers/

Real-time data streaming and event processing are critical components of modern distributed systems architectures. Apache Kafka has emerged as a leading platform for building real-time data pipelines and enabling asynchronous communication between microservices and applications. However, running and managing Kafka clusters at scale can be challenging, requiring specialized expertise and significant operational overhead.

Amazon Managed Streaming for Apache Kafka (Amazon MSK) is a fully managed service that you can use to build and run production Kafka applications. With Amazon MSK, you can rely on AWS to handle the heavy lifting of provisioning and managing Kafka clusters, while you focus on building innovative applications and real-time data processing pipelines.

In this post, you learn how AppFolio adopted Amazon MSK Express brokers to replace hours-long rebalances and manual storage planning with a streaming platform that scales automatically.

About AppFolio and its data streaming platform

AppFolio is a leading Real Estate Performance Management platform, serving thousands of property management companies across the United States. AppFolio’s platform processes millions of transactions daily, from rent collection and maintenance requests to lease management and financial reporting. In this data-intensive environment, reliable streaming infrastructure isn’t only important. It’s mission-critical.

At AppFolio, real-time data is the foundation of the company’s ability to deliver powerful, intelligent solutions that power the real estate industry. To achieve this level of performance, AppFolio engineered a modern streaming data architecture built on Amazon MSK with Express brokers. This infrastructure enables high-throughput, real-time applications at scale. With Amazon MSK Express brokers, AppFolio reliably ingests massive volumes of diverse data, including Change Data Capture (CDC) and server-side events, and makes it available to downstream consumers, such as real-time fraud detection, financial reporting, and automated property management workflows, within seconds of origin.

Previous architecture and AppFolio’s evolving requirements

Until early 2025, AppFolio ran their streaming platform on a single Amazon MSK cluster with Standard brokers, supporting both customer-facing and internal workloads. The architecture served them well through earlier growth phases. As AppFolio’s data platform evolved to support increasingly complex use cases and higher throughput, two characteristics of their workload led them to look for a more elastic streaming foundation.

AppFolio’s previous architecture: a single Amazon MSK cluster with Standard brokers serving both customer-facing and internal workloads

Figure 1: AppFolio’s previous architecture with Amazon MSK Standard brokers

First, AppFolio makes extensive use of log-compacted topics for their CDC streams. Compacted topics retain the latest value for each key indefinitely, which is exactly what they want for streams that mirror the state of operational tables. As their footprint grew, AppFolio wanted an infrastructure model that could scale storage automatically alongside data growth, without ongoing capacity planning that took multiple hours every month.

Second, AppFolio’s throughput continued to grow as they onboarded new use cases and added more event sources. They wanted the ability to scale the cluster quickly in response to traffic shifts, with minimal lead time for partition reassignments.

Third, as AppFolio’s platform matured, they needed workload isolation between customer-facing and internal data flows. Running customer-facing and internal workloads on a single cluster made it harder to size and tune each independently. As both grew, AppFolio wanted dedicated resources so each could be sized and tuned independently.

Based on these needs, AppFolio identified the following key requirements for their next-generation streaming platform:

  1. Elastic, automatically managed storage that scales with AppFolio compaction-heavy CDC workloads, removing the need for upfront broker capacity planning.
  2. Faster horizontal scaling and partition reassignment so AppFolio can adjust cluster shape in response to actual traffic in minutes rather than hours.
  3. Workload isolation between customer-facing and internal data flows, so each workload can be sized and tuned for its own traffic pattern.

Why AppFolio chose Amazon MSK Express brokers

After evaluating their options, AppFolio chose Amazon MSK Express brokers as the foundation for their next-generation streaming platform. Express brokers are a broker type offered under MSK Provisioned. They include pay-as-you-go elastic storage that scales automatically, intelligent partition rebalancing, and Kafka configuration defaults tuned for production workloads. Express brokers mapped directly to the requirements AppFolio identified:

  1. Elastic storage that scales with their data. Express brokers remove broker disk sizing and provisioning, with storage scaling automatically alongside data growth. AppFolio pays only for the storage actually used.
  2. AWS benchmarks showed up to 20 times faster scaling. Horizontal scaling and partition reassignment that previously took hours now complete in minutes, letting AppFolio react to traffic shifts on a much shorter cycle.
  3. Production-tuned defaults. Express brokers come pre-configured with Kafka best-practice defaults and built-in client throughput quotas, simplifying AppFolio’s operational model.
  4. Full Kafka API compatibility. AppFolio was able to migrate without changes to its producer and consumer applications.

As part of the migration, AppFolio also took the opportunity to rethink how the cluster was being used. Rather than recreating a single shared cluster on Express brokers, they segmented their MSK clusters by workload type. This gives customer-facing and internal workloads dedicated resources, providing better isolation and more predictable performance for each workload class.

Current architecture

AppFolio’s current architecture consists of multiple Amazon MSK clusters with Express brokers, segmented by workload type. Each cluster is sized and tuned for its specific traffic pattern, providing improved isolation and more predictable performance. The following diagram shows the deployment.

Current architecture: multiple Amazon MSK clusters with Express brokers, segmented by workload type into customer-facing and internal clusters

Figure 2: Current architecture with workload-segmented Amazon MSK clusters using Express brokers

Benefits achieved

By migrating to Amazon MSK Express brokers and adopting a workload-segmented cluster design, AppFolio has realized several key benefits:

Elastic, hands-off storage

The pay-as-you-go storage of Express brokers scales automatically with AppFolio’s data growth. Storage capacity is no longer something the platform team plans, provisions, or monitors, and AppFolio pays only for what they use. For a workload that runs heavily on compacted topics, this is the single largest operational improvement they have seen.

Faster scaling

Partition reassignment and broker scaling that previously took hours now complete in minutes, enabling AppFolio to adjust cluster shape in response to actual traffic instead of running ahead of forecasts.

Improved workload isolation

Splitting their streaming traffic into workload-segmented clusters has given AppFolio more predictable performance. Customer-facing and internal workloads now run on dedicated infrastructure, and each cluster can be sized and tuned for its own traffic pattern.

Stable environment as data volumes grow

Since the migration, AppFolio has maintained a stable environment with no significant downtime, even as data volumes continue to grow.

Reduced operational overhead

Hands-off storage management and intelligent rebalancing have removed several recurring tasks from the AppFolio platform team’s queue, including the constant monitoring and manual intervention that storage planning required under their previous architecture.

Conclusion

By using Amazon MSK Express brokers and adopting a workload-segmented cluster design, AppFolio has built a streaming foundation that scales elastically with their data growth and adapts quickly to changes in traffic. The pay-as-you-go storage and faster scaling of Express brokers let AppFolio’s platform team focus engineering effort on building new capabilities for customers, rather than on Kafka capacity planning. As AppFolio continues to expand its platform for the real estate industry, the Amazon MSK Express brokers infrastructure provides a scalable foundation for future growth.

To learn more about Express brokers for Amazon MSK, see the Express brokers for Amazon MSK documentation and the AWS announcement post Introducing Express brokers for Amazon MSK.


About the authors

Brandon Stanley

Brandon Stanley

Brandon is a Staff Data Engineer at AppFolio, responsible for architecting, building, and evolving AppFolio’s near real-time data platform, which captures, ingests, and serves database change logs, custom server-side events, and clickstream events from customer databases across product domains to targets including data warehouses, OLTP databases, and data lakehouses.

Devarsh Patel

Devarsh Patel

Devarsh is a Data Engineer at AppFolio, where he builds and operates large-scale, production-grade streaming data infrastructure that powers real-time analytics across the organization. His areas of focus include change data capture (CDC) pipelines, Apache Flink, Snowflake, and AWS infrastructure automation using Terraform and Kubernetes.

Ryan D’Souza

Ryan D’Souza

Ryan is a Staff Data Engineer at AppFolio. He architects, builds, and scales the data platform powering AppFolio’s AI solutions, customer-facing applications, and product analytics. He specializes in streaming data pipelines and data lakehouse architectures on AWS.

Aarjvi Desai

Aarjvi Desai

Aarjvi is a Sr Technical Account Manager and container specialist at AWS, based in the San Francisco Bay Area. She helps customers solve cloud challenges and build scalable, reliable solutions for generative AI workloads. Her expertise spans Kubernetes architecture, GPU accelerated workloads, and helping enterprises navigate AI infrastructure at scale.

Kalyan Janaki

Kalyan Janaki

Kalyan is Senior Big Data & Analytics Specialist at AWS. He helps customers architect and build highly scalable, performant, and secure cloud-based solutions on AWS.

Shilpa Bondale

Shilpa Bondale

Shilpa is a Senior Solutions Architect at AWS, based in the San Francisco Bay Area. She partners with companies to solve complex engineering challenges across databases, analytics, machine learning, and AI. She helps customers architect scalable, production-grade solutions, from real-time data pipelines to large-scale ML inference – using the breadth of AWS services.

Streamline Apache Kafka cluster operations and migrations with Agent Skills for Amazon MSK

Post Syndicated from Huyam Hasan original https://aws.amazon.com/blogs/big-data/streamline-apache-kafka-cluster-operations-and-migrations-with-agent-skills-for-amazon-msk/

Amazon Managed Streaming for Apache Kafka (Amazon MSK) manages core operational tasks for running Apache Kafka, including cluster provisioning, patching, high availability, and more. But operating Kafka clusters at scale still involves decisions that benefit from deep domain knowledge. For example, where do I start investigating application latency? How do I right-size a cluster to balance performance and cost? How do I analyze my applications, cluster configurations, and other requirements to support a smooth migration from self-managed Kafka to Amazon MSK?

With the new Agent Skills for Amazon MSK, you can access AI-assisted guidance for operations and migration planning directly in your development environment. Two complementary skills, managing-amazon-msk and migrate-to-msk, encode domain expertise based on AWS best practices, structured troubleshooting workflows, and programmatic sizing and compatibility analysis.

In this post, we walk through installing both skills and demonstrate their key capabilities. These include diagnosing a performance issue, sizing a cluster with cost breakdowns, and migration planning from self-managed Kafka to Amazon MSK including discovery, compatibility assessment, and target sizing.

How Agent Skills enhance documentation

Baseline large language models encode knowledge from their training data. That data can go stale as services evolve, and it often lacks the specific, contextual detail a task needs. As a result, a general-purpose assistant can produce answers that sound convincing but are factually wrong (hallucinations). For example, Amazon MSK Provisioned clusters come in two broker types, Standard and Express. Both broker types include their own considerations to achieve your performance, latency, availability, and durability requirements. Because training data mixes the two together, general-purpose assistants routinely conflate them and apply advice to the incorrect broker type.

These skills solve this problem by encoding the correct context for Amazon MSK broker operations, performance management, client configuration, and migrations, aligned with AWS best practices. This helps agents give more accurate, contextual guidance.

Overview of solution

The two Amazon MSK Agent Skills cover the full lifecycle of Amazon MSK cluster ownership:

Skill 1: managing-amazon-msk

Operations expertise for Amazon MSK Provisioned clusters with both Standard and Express broker types:

Workflow What it does
Performance troubleshooting Structured decision tree: CPU saturation, batch size analysis, Amazon Elastic Block Store (Amazon EBS) throughput entitlements (Standard), Express brokers entitlements
Consumer lag diagnosis Determines if lag is broker-side, partition-level (hot keys), or client-side. Provides targeted fixes
Storage management Amazon EBS expansion, auto scaling, retention planning, tiered storage (Standard only)
Cluster sizing and pricing Programmatic right-sizing and cost estimate tool comparing all Standard and Express instance types with cost breakdowns
Monitoring and alarms Set up actionable Amazon CloudWatch alarms with broker-type-aware thresholds that follow best practices for monitoring
Maintenance operations Rolling restart impact analysis, patching and broker upgrades, version upgrade planning, and transient failure analysis (distinguishing expected maintenance disruptions from real issues).

Skill 2: migrate-to-msk

Migration planning from self-managed Apache Kafka to Amazon MSK in three phases:

Phase What it does
Discovery Inventories your source cluster from infrastructure as code (IaC) files, Kafka CLI output, or manual input. Produces a standardized cluster-config.json
Assessment Five-pillar compatibility check (topology, version, configs, auth, quotas) plus target cluster sizing using the AWS-published Amazon MSK Sizing and Pricing workbook
Simulation (Optional) Deploys temporary Amazon MSK cluster and Amazon EC2 load-generation fleet in your account to test performance under synthetic load before you migrate. Produces an Amazon CloudWatch dashboard with throughput, broker health, latency, and consumer lag metrics.

After assessment, the skill provides guidance on using Amazon MSK Replicator for the actual data migration to your new Amazon MSK cluster.

Prerequisites

To use the tool, you need:

  • An AI coding assistant that supports Agent Skills, such as Kiro IDE, Amazon Q Developer, or any tool that supports the Model Context Protocol (MCP).
  • AWS Command Line Interface (AWS CLI) version 2.35.0 or later.
  • Python 3.12+ and uv installed (Python package runner used by the migrate-to-msk skill).
  • Agent Toolkit for AWS and AWS MCP server installed.
  • An AWS Identity and Access Management (IAM) role configured with access scoped to each skill’s needs:
    • For managing-amazon-msk:
      • Permissions to describe and manage Amazon MSK clusters, retrieve Amazon CloudWatch metrics for performance diagnostics, and create and delete CloudWatch alarms.
    • For migrate-to-msk:
      • Optional read-only access (CloudWatch metrics, describe clusters) to gather runtime metrics from an existing AWS estate for a more accurate assessment.
      • The optional Simulation phase requires permissions to create AWS CloudFormation stacks.

Installing the AWS MCP server and skills

Both skills are available in the Agent Toolkit for AWS on the GitHub website.

After initial setup following the steps in the Agent Toolkit instructions, install the Amazon MSK skills with:

aws agent-toolkit add-skill --skill-name managing-amazon-msk
aws agent-toolkit add-skill --skill-name migrate-to-msk

For more information on managing skills, refer to Managing skills with the AWS CLI in the Agent Toolkit for AWS User Guide.

Verify MCP installation by checking the MCP server status in your IDE’s MCP panel.

Verify skill installation with:

aws agent-toolkit list-installed-skills

You should see both skills listed for your detected agents. To confirm they’re active, ask your AI assistant an Amazon MSK question, and it should load the skill to engage with broker-type-aware guidance.

Scenario 1: Diagnosing high latency

During your evaluation of Amazon MSK your team notices elevated produce latency. You ask the AI assistant for help,

“Our Amazon MSK Express broker cluster is experiencing high produce latency that we think is related to our client application. The producer code is in this working directory. Can you help diagnose?”

AI assistant recognizing the latency question and activating the managing-amazon-msk skill

The agent immediately identifies that this question would be well suited for the managing-amazon-msk-skill and activates it. In the same step, the agent opens your producer code to diagnose the real client configuration. The skill ships with reference guides, and the agent selects the two that matter for this specific problem. It then maps your application code directly onto the skill’s diagnostic workflow, landing on a diagnosis:

Skill mapping the producer code to its diagnostic workflow and reaching a latency diagnosis

The skill identifies three compounding anti-patterns in the configuration, specifically linger.ms=0, an undersized batch.size, and compression.type=none. It then explains why they negatively impact Kafka cluster performance: every tiny message becomes its own produce request, saturating broker request-handler threads. Based on these observations, the skill delivers a targeted solution:

Skill’s targeted fix for the linger.ms, batch.size, and compression.type client anti-patterns

The skill uses best practice client-configuration references to provide specific recommendations to improve your application. It then goes on to provide additional context, considerations, and the Amazon CloudWatch metrics to observe to verify that the configurations have improved your end-to-end performance.

Skill listing the Amazon CloudWatch metrics to watch after applying the configuration changes

You can try this yourself by bringing your own producer code and letting the skill diagnose it. If you give it access to the AWS CLI the agent can pull live Amazon CloudWatch metrics from your actual cluster. This lets it correlate broker-side signals with what it sees in your client configuration for a more complete diagnosis.

Scenario 2: Migrating to Amazon MSK Express brokers

The migrate-to-msk skill guides you through a structured migration from self-managed Apache Kafka to Amazon MSK in three phases: discovery, assessment, and optional simulation. When you prompt the skill, it launches the discovery phase.

Phase 1: Discovery — analyze your source cluster

In this scenario, you point the skill at your infrastructure as code (IaC) files describing a self-managed Kafka deployment:

“Here’s our Kafka infrastructure, can you help us plan a migration to Amazon MSK Express brokers?”

migrate-to-msk skill starting the discovery phase against the source Kafka infrastructure

The skill pulls static details: broker topology, versions, security configuration, and topic definitions directly from your IaC files.

Skill extracting broker topology, versions, security, and topics from the IaC files

For runtime values the skill can’t derive from IaC, such as actual peak throughput or consumer-group count, the skill identifies these as flagged gaps. For each gap, the skill provides the specific Kafka CLI commands you can run against your live cluster to capture those values.

Skill listing runtime-value gaps and the Kafka CLI commands to capture them

The skill supports discovery from multiple source types: Terraform, CDK, CloudFormation, Docker Compose, Kubernetes manifests, or manual input in conversation.

Phase 2: Assessment — validate compatibility and size the target

With discovery complete, the assessment phase runs two independent analyses against your current cluster infrastructure.

Compatibility assessment evaluates your source cluster across five pillars:

Pillar What it checks
Topology AZ count, broker count, KRaft or ZooKeeper
Kafka version Source version against Amazon MSK supported set (3.6, 3.8, 3.9)
Configs Broker and topic configs against Amazon MSK’s editable/enforced/range-restricted sets
Auth Authentication mechanism compatibility
Quotas Peak workload against Amazon MSK per-broker ceilings

Each pillar produces one of the following finding types:

Verdict Meaning
INFO Already aligns with Amazon MSK. No action needed.
ADVISORY Amazon MSK handles this differently, but migration can proceed. Review so the behavior change is expected.
ACTION_REQUIRED Amazon MSK will not accept this in its current form. Remediation recommended.

Target sizing uses your current cluster’s usage metrics to perform right-sizing for Amazon MSK, including instance type, broker count, and projected monthly cost for your workload. This gives you a shareable artifact to use for sizing against different inputs and assumptions.

Next, you ask the skill to run the assessment:

“Assess my cluster for Amazon MSK Express broker compatibility and size the target”:

Skill running the compatibility assessment and target sizing for Amazon MSK Express brokers

The skill runs both analyses against your cluster configuration. It outputs a compatibility report, sizing inputs, and sizing outputs, giving you a complete picture of what needs attention before migration and what your target cluster should look like.

Assessment output with the compatibility report, sizing inputs, and sizing outputs

Once you’ve validated compatibility and provisioned your Amazon MSK Express brokers, Amazon MSK Replicator handles the actual data migration. Amazon MSK Replicator is the native AWS solution for replicating data between Amazon MSK Provisioned clusters. For migrations, it supports replication of data from self-managed Apache Kafka clusters (including on-premises, self-hosted on AWS, or other cloud providers) to Amazon MSK Provisioned clusters.

Phase 3: Simulation (optional) — validate performance before cutover

With assessment complete, you can optionally ask the skill to guide you through setting up a live test environment:

“Can we run a simulation to see how Amazon MSK Express brokers handle our workload before we commit to migrating?”

Skill outlining the temporary Amazon MSK Express and Amazon EC2 simulation before deployment

The skill walks you through deploying temporary Amazon MSK Express brokers and EC2 client fleet in your own AWS account. These are sized from your Phase 2 workbook or numbers you provide, so that you can see real performance on your actual workload rather than relying on estimates. It confirms the target account and permission before deploying any billable resources.

Once the cluster is up, you choose a provided test (end-to-end latency or broker restart under load), and the skill runs it. It then surfaces metrics related to throughput, broker health, latency, and consumer lag on a CloudWatch dashboard. When you’re done, the skill helps you tear the stack down so you stop incurring cost.

Scenario 3: Sizing a cluster with cost breakdowns

You’re planning a new streaming workload and need to determine the right configuration:

“Size an Amazon MSK cluster for 200 MiB/s peak ingress, 600 MiB/s peak egress (3 consumer groups), 1,500 partition replicas, 168 hours retention. Compare Standard and Express.”

Sizing calculator evaluating the workload against Standard and Express instance types

The skill’s programmatic sizing calculator evaluates your workload against every available instance type simultaneously, sizing across four constraints: ingress capacity, egress capacity, partition limits, and storage volume. Each is rounded up to a multiple of 3 Availability Zones (AZs).

When you ask the skill to size a cluster, it uses its sizing script to identify and recommend the least expensive viable option per broker class, and to break down the cluster cost across various sizing dimensions.

Sizing output recommending the least expensive viable broker per class with a cost breakdown

The calculator accounts for factors that manual sizing often misses, such as replication overhead on EBS, network bandwidth, and cross-AZ data transfer costs. The skill flags exactly which constraint is the bottleneck for each instance type, so you understand why a particular broker count was chosen.

Sizing results flagging the bottleneck constraint that sets the broker count per instance type

Security considerations

Both skills recommend Transport Layer Security (TLS) encryption and IAM authentication. Discovery and assessment outputs contain broker addresses and configuration details. Treat them as sensitive and avoid sharing them in public channels without redaction. The migration artifacts do not store passwords or secrets.

Cleaning up

If you ran the optional Simulation phase with the migrate-to-msk skill, it deployed real resources in your AWS account, including an Amazon MSK Express cluster and an EC2 load-generation fleet, that continue to incur charges until you delete them. Ask the skill to tear down the simulation, or delete its CloudFormation stack yourself, to stop incurring cost. Only one simulation can exist per account at a time.

Migration artifacts (migrate-to-msk-skill-artifacts/) are local files that you can delete at your discretion.

Conclusion

Traditionally, Kafka administrators have relied on web-based UIs and dashboards for cluster health management and troubleshooting. With these skills, you can accelerate agent workflows that integrate directly into development environments and DevOps processes. Amazon MSK aims to expand this Agent Skills portfolio with additional tools and capabilities, so customers can build more sophisticated agentic DevOps workflows for their streaming infrastructure.

The Amazon MSK Agent Skills bring structured, broker-type-aware expertise to operating and migrating Amazon MSK clusters. Instead of searching through documentation to determine whether a metric applies to Standard or Express, or manually cross-referencing compatibility matrices for a migration, you get targeted guidance that routes to the correct path based on your cluster’s actual configuration.

Get started by installing both skills from the Agent Toolkit for AWS on the GitHub website into your development environment. Then try a prompt like:

“Size Amazon MSK Express brokers for 100 MiB/s ingress with 3 consumer groups and 72-hour retention”

or

“My Amazon MSK Express brokers have high produce latency. Help me diagnose”

The skills support you at any stage in the cluster lifecycle.

To learn more, visit the Amazon MSK documentation or open the Amazon MSK console. Have questions or feedback? Open an issue in the Agent Toolkit for AWS repository on the GitHub website.


About the authors

Huyam Hasan

Huyam Hasan

Huyam is a Solutions Architect II at AWS, based in Austin, TX, with a passion for data and analytics solutions and customer success. She works with enterprise customers across travel, gaming, and hospitality to design and build modern, secure, and scalable data and streaming architectures, with a focus on real-time analytics that help them achieve their business outcomes.

Ashley Millette

Ashley Millette

Ashley is a Specialist Solutions Architect for Streaming and Analytics at AWS. She partners with customers to design and implement real-time data streaming architectures using services like Amazon MSK helping them build scalable, cost-effective pipelines that turn data in motion into actionable insights. She is passionate about simplifying complex streaming workloads and enabling customers to modernize their data infrastructure with confidence.

Deliver Apache Kafka data to streaming tables for Apache Iceberg with Amazon MSK Express brokers

Post Syndicated from Shakhi Hali original https://aws.amazon.com/blogs/big-data/deliver-apache-kafka-data-to-streaming-tables-for-apache-iceberg-with-amazon-msk-express-brokers/

Today, we are announcing delivery to streaming tables on Apache Iceberg for Amazon Managed Streaming for Apache Kafka (Amazon MSK) Express brokers, a fully managed capability that continuously materializes your streaming data as queryable Apache Iceberg tables on Amazon S3 Tables, a capability of Amazon Simple Storage Service (Amazon S3). With delivery to streaming tables, you no longer need to deploy, scale, or maintain Kafka connectors, Flink jobs, or custom consumers to make your streaming data available for analytics. You select a Kafka topic, choose S3 Tables as your destination, and your data becomes a read-only Iceberg table queryable from Amazon Athena, Amazon Redshift, and Apache Spark within minutes. Delivery to streaming tables provides up to 60% cost savings compared to self-managed alternatives. It also reduces downstream query costs by up to 30% through optimized file sizing, without writing a single line of code or managing any infrastructure. Because this capability delivers to S3 Tables registered in AWS Glue Data Catalog, your tables are automatically discoverable through Glue Data Catalog Business Context and Semantic Search (preview). Data stewards can enrich streaming tables with business descriptions, glossary terms, and skill assets. AI agents can then discover and reason in real time using semantic search grounded in trusted business definitions rather than raw schema inference.

In addition to S3 Tables, you can deliver Amazon MSK streaming data to general purpose Amazon S3 buckets in source data format. Data delivery to general purpose Amazon S3 buckets enables workloads like archival, backup, or ML training data delivery. This provides a price-performant, serverless, and scalable way to deliver streaming data as-is to your general purpose Amazon S3 buckets.

Challenges with delivering streaming data to Apache Iceberg

Customers today face three critical challenges when integrating streaming data with Apache Iceberg. First, ease of use: customers must manage complex Kafka Connect deployments, handle frequent pipeline failures, maintain custom configurations, handle data format conversions, and manage pipeline infrastructure for data delivery. These operational tasks consume significant engineering time and introduce ongoing risk of downtime. Second, resiliency: without proper coordination, simultaneous writes from multiple high-throughput Kafka partitions can conflict with each other, leading to failed commits, data freshness delays, and performance issues. Streaming ingestion of high-volume data creates large numbers of small Parquet files in Iceberg tables, significantly degrading query performance and forcing a difficult trade-off between data freshness and query efficiency. Third, price performance can become a bottleneck to enriching your data lake with streaming data into. With delivery to streaming tables, pricing is predictable, and up to 60% lower than self managed Kafka deployments, lowering the barrier to getting real-time context to your data agents.

How delivery to streaming tables solves these challenges

Delivery to streaming tables is a native capability built directly into Amazon MSK Express brokers. It addresses each challenge directly: it eliminates operational complexity by removing the need to deploy, configure, or maintain pipeline infrastructure, you enable it with a few clicks. It provides built-in write coordination and exactly-once delivery semantics, resolving concurrent writer conflicts and supporting data integrity without manual intervention. And it performs intelligent inline compaction during ingestion, producing query-optimized Parquet files that eliminate the small-file problem while maintaining minute-level data freshness. The capability automatically scales to process gigabytes per second of throughput.

End-to-end managed streaming analytics architecture

With delivery to streaming tables, you now have a fully managed end-to-end real-time data architecture from data ingestion through storage to analytics. Your producers publish events to Amazon MSK Express brokers, which continuously deliver data as optimized Iceberg read-only tables in S3 Tables, registered automatically on AWS Glue Data Catalog. From there, you can query your streaming data using analytics engines like Amazon Athena, Amazon Redshift, Amazon EMR (Apache Spark), or Apache Flink . You can also let AI agents discover and reason over your data through Glue Data Catalog semantic search. This managed experience eliminates the intermediate infrastructure that customers previously assembled, no separate connector clusters, no compaction jobs, no custom consumers, replacing it with a single, serverless pipeline from stream to insight.

The following diagram illustrates this end-to-end architecture.

End-to-end streaming architecture from Amazon MSK Express brokers to Iceberg tables in Amazon S3 Tables, queried by Athena, Redshift, EMR, and Flink

Getting started

To get started, log into the Amazon MSK console, navigate to your Amazon MSK Express cluster, and enable delivery to streaming tables with a few clicks. Specify the Kafka topic you want to deliver, configure your schema settings using AWS Glue Schema Registry, and choose your destination. Destinations can be either fully managed Iceberg tables in S3 Tables or self-managed Iceberg tables in general purpose S3 buckets. Once enabled, delivery to streaming tables immediately begins materializing your Kafka data as queryable Iceberg tables in S3 with no further intervention required.

Additionally, you can use Amazon MSK APIs to programmatically set up, update, or delete delivery to streaming tables configurations for your Kafka topics. This allows teams to build agentic workflows and infrastructure-as-code patterns for teams managing configurations across multiple clusters and topics at scale.

Getting started with the streaming tables Agent Skill

The streaming tables Agent Skill provides AI-assisted guidance for setting up streaming tables integrations for your existing or new topics in Amazon MSK Express cluster. The skill helps you configure delivery to S3 Tables (Iceberg) or S3, including schema registry setup, IAM role configuration, and validation.

Installing as an Agent Skill

Agent Skills are discovered automatically by compatible tools through the SKILL.md file. Refer to the Agent Toolit for AWS Skill Installation Guide to install the managing-amazon-msk Agent Skill. We also recommend you install the AWS MCP Server in your developer tool of choice, which exposes tools for searching AWS documentation, blogs, and Skills dynamically at runtime. These capabilities make agents more accurate and powerful for AWS related development and operational tasks, and make skill discovery and installation more flexible. Refer to Setting up the AWS MCP Server for guidance on installing the AWS MCP Server in your environment.

For example:

aws configure agent-toolkit
aws agent-toolkit add-skill --skill-name managing-amazon-msk

To verify the installation, interact with the skill in your preferred tool.

To start delivering data from your Kafka topics to Apache Iceberg tables in real time, for example, prompt “Create me a streaming table on my MSK cluster for my events topic” to your agent of choice:

Agent chat showing the prompt to create a streaming table on an MSK cluster for the events topic

The agent will dynamically load the managing-amazon-msk skill, and start by gathering the available resources in your AWS account to use for the streaming tables integration. Once it gathers that data, it will confirm the resources to use or create, and create the integration:

Agent confirming the AWS resources to use and creating the streaming tables integration

After creating the integration, the agent will summarize the status and can then help with any other operational tasks with your data. For example, the agent can help you set up AWS Lake Formation permissions for you to query the data in S3 Tables with Athena, or configure your table maintenance behavior in S3 Tables:

Agent summarizing integration status and offering to set up Lake Formation permissions or configure S3 Tables maintenance

Conclusion

Delivery to streaming tables and general purpose S3 buckets is available in all AWS Regions where Amazon MSK Express brokers are available. To learn more about delivery to streaming tables, visit the documentation and pricing pages.


About the authors

Shakhi Hali

Shakhi Hali

Shakhi is a Product Manager for Amazon Managed Streaming for Apache Kafka. She works closely with AWS customers to understand their needs for real-time analytics and high throughput, low latency streaming workloads. Working backwards from their needs, she helps drive the Amazon MSK roadmap and deliver new innovations that help AWS customers focus on building novel streaming applications.

Mazrim Mehrtens

Mazrim Mehrtens

Mazrim is a Sr. Specialist Solutions Architect for messaging and streaming workloads. Mazrim works with customers to build and support systems that process and analyze terabytes of streaming data in real time, run enterprise Machine Learning pipelines, and create systems to share data across teams seamlessly with varying data toolsets and software stacks.

Huyam Hasan

Huyam Hasan

Huyam is a Solutions Architect II at AWS, based in Austin, TX, with a passion for data and analytics solutions and customer success. She works with enterprise customers across travel, gaming, and hospitality to design and build modern, secure, and scalable data and streaming architectures, with a focus on real-time analytics that help them achieve their business outcomes.

How Razorpay Built Real-Time Anomaly Detection with Amazon MSK

Post Syndicated from Narendra Kumar original https://aws.amazon.com/blogs/big-data/how-razorpay-built-real-time-anomaly-detection-with-amazon-msk/

When you process over 500 million transactions per month, every second of undetected anomaly means failed payments, lost revenue, and eroded merchant trust. Static monitoring thresholds that worked for thousands of merchants collapse at the scale of millions, and the cost of missed detection compounds exponentially.

In this post, we explore Razorpay’s anomaly detection and alerting platform (ADA) architecture using Amazon Managed Streaming for Apache Kafka (Amazon MSK) and other AWS services. According to Razorpay the system detects transaction anomalies in under 30 seconds, supports thousands of merchant-level alerts, and reduced monitoring costs by approximately 80 percent. The platform maintains 99.99 percent uptime for over 500 million transactions per month.

Founded in 2014, Razorpay has become one of India’s largest full-stack financial solutions companies, powering payments, banking, and business growth for over 10 million businesses. With offerings spanning payment gateway, RazorpayX for business banking, and Razorpay Capital for lending, the company processes over 500 million transactions per month across payments, payroll, banking, and cross-border services.

At this scale, Razorpay’s data platform processes more than 5 billion events daily. Every transaction, settlement, and disbursement generates events that must be monitored in real time for anomalies. These range from systemic degradations and latency regressions to card-testing fraud attacks and velocity abuse at the merchant level.

For a regulated payments platform, undetected anomalies carry consequences far beyond technical metrics. A missed fraud pattern can mean direct financial losses running into millions of rupees. It can also bring regulatory scrutiny from the Reserve Bank of India and irreversible damage to merchant confidence, the foundation of Razorpay’s business. Razorpay needed real-time anomaly detection, but the existing infrastructure couldn’t keep pace with the company’s growth.

The problem: When static thresholds can’t keep up with scale

As Razorpay scaled from thousands to millions of merchants, the existing monitoring infrastructure hit critical limitations across four dimensions.

Anomaly blind spots

Systemic degradations, latency regressions, and success-rate drops went undetected until customers complained. By the time a human operator noticed a 15 percent drop in payment success rates for a specific gateway-merchant combination, thousands of transactions had already failed.

Fraud at velocity

Card-testing activity, velocity abuse, and geo-anomalies at the merchant level required sub-minute detection. Unauthorized users could generate hundreds of micro-transactions in seconds. Traditional batch detection was too slow to prevent damage.

Static thresholds don’t scale

The existing tooling relied on static thresholds with no adaptive baselines. This created a painful dilemma: set thresholds too tight and drown in false alarms (alert fatigue), or set them too loose and miss real incidents.

High cardinality equals high cost

Monitoring thousands of merchants individually on the previous architecture cost approximately $500K per year: $250K in licensing fees plus $250K in infrastructure, with fundamental scalability limits. ThirdEye queried a 21-day lookback at query time, enforcing a 1–2 minute service level agreement (SLA) minimum. The system was not designed for thousands of concurrent merchant-level alerts, a limitation confirmed by the vendor.

Solution overview: ADA: Anomaly detection and alerting

Razorpay built ADA (Anomaly Detection and Alerting), a configurable, multi-tenant engine for real-time anomaly detection and fraud prevention. The platform’s design centers on three core principles that address the limitations of the previous architecture.

First, ADA is declarative: users express what to detect, not how. A single domain-specific language (AdaDSL) drives both batch and streaming execution, eliminating the need for engineers to write custom detection code for each new alert. Second, ADA is adaptive. Dynamic baselines incorporate calendar-aware patterns (day-of-week, time-of-day, holiday adjustments) and machine learning (ML)-compatible thresholds that replace brittle static rules. Third, ADA is inherently multi-tenant: Payments, Payroll, and Banking each operate with isolated detection logic while sharing underlying infrastructure. This design removes the need to maintain separate monitoring stacks per business unit.

Amazon MSK serves as the event backbone of ADA, ingesting transaction events, distributing detection rules, and connecting the components of the real-time pipeline.

ADA architecture with Amazon MSK as the event backbone connecting event producers, Apache Flink stream processing, ClickHouse baselines, and alert consumers

Architecture: Amazon MSK as the streaming backbone

The ADA architecture positions Amazon MSK as the core integration layer connecting event producers to detection engines and alert consumers. Payment authorization, settlement, and disbursement events flow through Kafka topics managed by Amazon MSK. With Razorpay processing over 500 million transactions per month and 5 billion events daily, the ingestion layer must absorb high throughput with zero data loss.

High-throughput event ingestion

The architecture uses tenant-partitioned topics. Each business unit (Payments, Payroll, Banking) publishes to logically isolated topics while sharing physical infrastructure. This design supports independent consumer groups per tenant with predictable throughput guarantees.

Change Data Capture (CDC) events from Razorpay’s core transactional databases (Amazon Aurora MySQL-Compatible Edition) flow through Debezium and a Kafka Streams-based Harvester service into Amazon MSK. Application events from payment services also publish directly to Amazon MSK topics via native Kafka producers.

Why Amazon MSK as the backbone

Amazon MSK serves as the architectural backbone of ADA, fulfilling four critical functions that together support reliable, real-time anomaly detection at scale. At the ingestion layer, Amazon MSK absorbs the full stream of transaction events with three-replica durability. If downstream consumers experience an outage, they resume from their last committed offset without data loss. Beyond ingestion, Amazon MSK is the event distribution backbone of detection rules. AdaDSL definitions authored by domain experts are serialized and published to a dedicated Kafka snapshot topic, which Flink jobs consume as a broadcast stream.

This delivers hot-reloadable rule updates without pipeline restarts, a critical capability when detection logic must evolve daily. Amazon MSK further supports tenant isolation at the topic level. Payments, Payroll, and Banking events flow through isolated topic partitions that support independent scaling and consumer group management per business unit. Finally, Amazon MSK fully decouples event producers from detection consumers, meaning new detection logic can be deployed, scaled, or rolled back without touching production payment flows.

Apache Flink acts as the stateful stream processing engine between Amazon MSK and the detection/alerting layer. The Flink pipeline implements five key stages:

  1. Kafka Source (tenant-partitioned topics) – Consumes events from Amazon MSK with exactly-once semantics using Flink’s Kafka connector.
  2. Event-Time Assignment + Watermarking – Assigns event timestamps and generates watermarks with a late-arrival tolerance of 2× the window size.
  3. KeyBy (tenant_id, entity_key) + Windowed Aggregation – Partitions the stream by tenant and merchant, then computes windowed aggregates (success rates, latencies, transaction volumes).
  4. Async I/O – Baseline Fetch from ClickHouse. Non-blocking lookups against pre-computed baselines stored in ClickHouse, supporting 1,024 concurrent requests.
  5. Rule Evaluation (threshold / ML / CEP) – Evaluates AdaDSL rules against the enriched stream. This includes Complex Event Processing (CEP) patterns for sequence detection (for example, five consecutive declines followed by a success, a signature of card-testing fraud).

The pipeline outputs to three sinks:

  • anomalies_fct to ClickHouse for anomaly persistence and historical analysis.
  • Alert Gateway to Slack/PagerDuty for immediate notification.
  • windows_fct for reconciliation against batch baselines.

AdaDSL: Declarative detection at scale

AdaDSL abstracts detection logic into human-readable declarations that platform engineers and domain experts can author without understanding the underlying execution mechanics. A single definition compiles to both a ClickHouse Materialized View selector and a Flink CEP pattern, supporting consistent detection semantics across batch and streaming modes.

AdaDSL updates are distributed via the Amazon MSK snapshot topic. When an engineer modifies a rule, it’s serialized to Kafka and consumed by Flink as a broadcast state update. The change propagates to all running pipeline instances without redeployment. This is an important architectural advantage: the detection logic evolves independently of the infrastructure.

Reliability and fault tolerance

The architecture delivers 99.99 percent availability through multiple layers of resilience:

  • Amazon MSK is deployed across three Availability Zones with replication.factor=3 and min.insync.replicas=2, paired with producer-side acks=all. No single broker failure causes data loss or ingestion interruption, because the durability guarantee depends on all three settings working together. Combined with configurable retention policies, Amazon MSK provides a meaningful replay window for consumer recovery.
  • Flink checkpointing to Amazon Simple Storage Service (Amazon S3) provides exactly-once processing semantics. If a Flink task fails, the job manager restores from the latest checkpoint and resumes processing from the corresponding Kafka offsets. No events are lost or duplicated.
  • Idempotent sinks: Dedupe keys (tenant:AdaDSL:version:entity:window_start) prevent reprocessed events from creating duplicate anomaly records or alerts.
  • Event-time watermarks: 2× window tolerance handles late-arriving events gracefully, supporting detection accuracy even under network delays.

Results and business impact

The migration from Pinot + ThirdEye to ADA on Amazon MSK and Apache Flink delivered measurable improvements. The platform achieved approximately 80 percent cost reduction compared to the previous architecture while maintaining a 99.99 percent uptime SLA. Anomaly detection latency in streaming mode is under 30 seconds, and the system processes over 5 billion events daily. It supports thousands of concurrent merchant-level alerts with full multi-tenant isolation across Payments, Payroll, and Banking.

Operational improvements

The ADA platform delivered significant operational improvements across detection accuracy, speed, and team autonomy:

  • Alert fatigue removed – Adaptive baselines with calendar-aware patterns (day-of-week, time-of-day, holiday adjustments) reduced false positives by over 90 percent compared to static thresholds.
  • Mean time to detection reduced from minutes to seconds – Sub-30-second streaming detection replaced batch detection cycles that previously required 1–2 minutes minimum.
  • Self-service detection – Domain experts in Payments, Payroll, and Banking teams author their own AdaDSL rules without requiring platform engineering involvement.
  • Unified platform – One system for anomaly detection, fraud detection, alert routing, and reconciliation across all business units.

Key learnings and best practices

Throughout the design and implementation of ADA, Razorpay identified several architectural principles that proved essential at scale:

1. Separate rule definition from execution

A declarative DSL lets domain experts define detection logic while the platform decides batch or streaming execution. This separation allowed Razorpay to scale the number of active detection rules from dozens to thousands without proportional engineering effort.

2. Use Amazon MSK as the unifying backbone

Kafka’s publish-subscribe model naturally decouples event producers from detection consumers. Beyond basic event transport, Amazon MSK serves as the distribution mechanism for rule updates (broadcast state), tenant isolation (topic partitioning), and fault tolerance (offset-based replay). Investing in the streaming backbone early benefited every subsequent design choice.

Flink excels at sub-minute, stateful detection. ClickHouse excels at deterministic baseline computation and historical context. Rather than forcing one engine to do both, the hybrid architecture plays to each engine’s strengths.

4. Design for multi-tenancy from day one

Shared infrastructure with tenant isolation (row-level security in ClickHouse, scoped topics in Amazon MSK, tenant-partitioned Flink pipelines) keeps operational costs low while serving multiple business units with independent SLAs.

5. Build for extensibility

A plugin-compatible architecture allows ML models (ETS/Prophet for forecasting), CEP patterns (Flink CEP for sequence detection), and custom root cause analysis (RCA) strategies to be added without platform-level changes. Razorpay’s roadmap includes large language model (LLM)-assisted RCA and autonomous AdaDSL generation.

Conclusion

Razorpay transformed its anomaly detection from static-threshold monitoring on Pinot + ThirdEye to an adaptive, real-time system on Amazon MSK and Apache Flink.

This reflects a pattern increasingly common among high-scale FinTech platforms: a reliable, high-throughput streaming layer is not an optimization. It’s a prerequisite for operating payment infrastructure at scale.

Amazon MSK forms the backbone that allows Razorpay to ingest 5 billion events daily and distribute detection rules in real time. It also isolates multiple business units on shared infrastructure and provides exactly-once processing guarantees for financial transaction monitoring. Apache Flink transforms those raw event streams into sub-30-second anomaly detection with CEP-based fraud pattern matching.

For platform engineers building real-time monitoring for financial services, the takeaway is clear. Invest in the streaming backbone early, design for declarative extensibility, and let managed services absorb the operational complexity of distributed stream processing.

If you’re building real-time monitoring for a high-throughput transactional system, start by evaluating your current architecture against the four limitations described in this post. These are anomaly blind spots, detection latency for fraud, static threshold scalability, and cost at high cardinality. From there, consider whether a declarative detection layer (separating rule definition from execution) could accelerate your team’s ability to ship new alerts without infrastructure changes. For a hands-on starting point, explore the Amazon MSK Labs workshop.

To learn more about Amazon MSK, visit the documentation.


About the authors

Narendra Kumar

Narendra Kumar

Narendra is a senior data platform and engineering leader with deep experience in building and operating large-scale data platforms for high-growth FinTech and SaaS organizations. He has worked across the full data lifecycle, including real-time data ingestion, modern lakehouse architectures, analytics platforms, and ML-ready data systems, with a strong focus on reliability, scalability, and cost efficiency.

Masudur Rahaman Sayem

Masudur Rahaman Sayem

Sayem is a Streaming Data Architect at AWS with over 25 years of experience in the IT industry. He collaborates with AWS customers worldwide to architect and implement data streaming solutions that address complex business challenges. As an expert in distributed computing, Sayem specializes in designing large-scale distributed systems architecture for maximum performance and scalability. He has a keen interest and passion for distributed architecture, which he applies to designing production-ready solutions at internet scale.

Sundar Sankaranarayanan

Sundar Sankaranarayanan

Sundar is a Data & Analytics Specialist at AWS with over 20 years of experience in the IT industry. He collaborates with AWS customers across India to architect and implement modern data analytics and Generative AI solutions. As an expert in data lakehouse architectures and cloud-native analytics, Sundar specializes in designing scalable real-time and batch data platforms that unlock business value at enterprise scale. He has a keen interest and passion for the convergence of data and AI, which he applies to helping organizations accelerate their cloud and AI journeys.

Deploy modern data platforms in minutes with MDAA

Post Syndicated from Sudeshna Dash original https://aws.amazon.com/blogs/big-data/deploy-modern-data-platforms-in-minutes-with-mdaa/

Modern Data Architecture Accelerator (MDAA) is an open source framework that replaces infrastructure code with concise YAML configuration, so your team can deploy a governed, production-ready data architecture, reducing deployment time from months to weeks (depending on complexity and team experience).

Organizations building modern data architecture on AWS face a critical challenge: deploying production-ready, governed infrastructure traditionally requires 6–12 months of custom development, thousands of lines of infrastructure code, and continuous remediation cycles to maintain security and compliance. Governance is often added incrementally, treated as an afterthought that creates compliance gaps and engineering rework.

MDAA addresses this by replacing infrastructure code with concise YAML configuration, achieving up to 97.6 percent code reduction (from approximately 1,800 lines of AWS CloudFormation to 45 lines of MDAA YAML) while embedding governance from the start. The complete Governed Lakehouse Starter Kit deploys 491 AWS resources across 12 stacks from approximately 450 lines of YAML configuration, representing a 66x verbosity ratio where each line automatically expands into production-ready infrastructure.

In this post, we explore how MDAA transforms data architecture development from months of manual coding to production-ready deployment through configuration-driven infrastructure and embedded governance, examine a real customer transformation, and provide a clear implementation pathway for your own data modernization journey.

Customer use case and challenge

A university system office needed to modernize its analytics architecture across 17 campuses while managing sensitive educational data. Their third-party dependency created bottlenecks that slowed feature implementation from weeks to months, and their IT team lacked the cloud skillsets to build modern infrastructure independently.

With MDAA, they achieved:

  • 95 percent reduction in time-to-value for dashboard and feature implementation (from weeks to hours).
  • 17 campuses integrated into a unified, secure architecture.
  • 7.2TB of data and over 8,000 dashboards migrated successfully.
  • Significant cost savings by removing third-party dependencies and reducing license costs.
  • Enhanced security posture for external stakeholders accessing sensitive educational data.

The team used MDAA to implement a modernization strategy with continuous integration and continuous delivery (CI/CD) for automated deployment. The architecture now supports rapid response to stakeholder requests while maintaining strict data governance through AWS Lake Formation.

Their transformation demonstrates what becomes possible when governance is embedded from launch rather than added incrementally, moving from months-long manual development to weeks of production-ready deployment through configuration-driven infrastructure.

Solution: MDAA and its value propositions

MDAA’s capabilities stem from its modular, composable architecture. The accelerator provides over 40 pre-built modules that encapsulate AWS best practices for security, governance, and operational excellence. Organizations describe the outcomes they want in MDAA-specific YAML configuration files (not CloudFormation or Terraform YAML) and the accelerator automatically translates these configurations into AWS Cloud Development Kit (AWS CDK) constructs, which then deploy via CloudFormation with embedded governance.

Configuration over code. The MDAA framework takes a fundamentally different approach: describe the outcomes you want in YAML, and the accelerator deploys production-ready infrastructure with embedded governance. Consider deploying a governed data lake where fraud detection teams need write access to transaction data, while marketing analytics teams require read-only access to customer behavior data. Traditional approaches require over 1,800 lines of CloudFormation across Amazon Simple Storage Service (Amazon S3) buckets, AWS Key Management Service (AWS KMS) keys, AWS Identity and Access Management (IAM) policies, and Lake Formation permissions. With MDAA, the same governed data lake is expressed in 45 lines of configuration, a 97.6 percent reduction, while helping you apply encryption, least-privilege access, and cross-account governance as built-in defaults.

The configuration deploys multi-zone S3 storage with KMS encryption, Lake Formation permissions with tag-based access control (TBAC) enabled, Amazon SageMaker Unified Studio for data product discovery, and encrypted AWS Glue Data Catalog with automated crawlers. All permissions flow through Lake Formation rather than individual IAM policies.

Embedded governance from day one. Governance is declared in YAML and deployed alongside infrastructure from the first run. Fine-grained access controls, encrypted data catalogs, data quality validation, audit trails, and sensitive data classification are all part of the same configuration. MDAA’s Governed Lakehouse starter kit defines an entire governed data architecture in roughly 450 lines of YAML, which produces approximately 29,700 lines of CloudFormation across 12 stacks (a 98.5 percent reduction in infrastructure code).

Modular, composable architecture. Each module is purpose-built to handle a specific capability within the data architecture. Modules communicate through AWS Systems Manager Parameter Store, passing resource identifiers (Amazon Resource Names (ARNs), IDs, and names) between stacks. This approach removes hardcoded dependencies. A KMS key created in one module can be referenced by another through parameter resolution, with all dependencies resolved automatically at deployment time.

The diagram illustrates the deployed architecture and team-level access flow that MDAA generates from the 45-line configuration.

Progressive architecture patterns. MDAA provides four reference architecture patterns that align to progressive stages of data infrastructure maturity:

  • Basic Data Lake deploys a governed data lake with built-in security controls, data quality checks, centralized metadata management using AWS Lake Formation and AWS Glue.
  • Data Science Platform extends the data lake with Amazon SageMaker notebooks, feature stores, and machine learning (ML) pipelines so data science teams can experiment and train models on governed data.
  • SageMaker Unified Studio adds a single interface for analytics and ML collaboration, connecting data engineers, analysts, and data scientists in one workspace.
  • Generative AI Platform layers Amazon Bedrock and Retrieval Augmented Generation (RAG) capabilities on top of your existing data foundation, so teams can build generative AI applications grounded in enterprise data.

Each pattern builds the one before it. You can start with the Basic Data Lake and adopt additional patterns as your team’s needs grow. MDAA’s modular design means you add capabilities without rearchitecting what you already deployed.

The infrastructure is versioned through GitHub, repeatable across environments, and auditable through comprehensive AWS CloudTrail logging. Data engineers focus on data pipelines and business logic while MDAA manages infrastructure complexity and governance integration. This represents the fundamental shift: from writing infrastructure code to describing the outcomes you want through configuration, with governance embedded from the start.

Use case of MDAA: Governed data architecture

DataOps teams spend significant time on governance tasks, including permissions management, compliance validation, and access control, rather than building pipelines and analytics. These aren’t data problems, they’re governance problems that consume engineering capacity meant for higher-value work. MDAA addresses this at the architectural level. Governance is declared in YAML and deployed alongside infrastructure from the first run.

The following sections walk through how each governance module works in practice.

Publish, discover, subscribe, and consume data products between business units: SageMaker Unified Studio

Amazon SageMaker Unified Studio provides a governed data catalog where data producers publish data products, and consumers discover and subscribe to them. Your deployment with MDAA includes a pre-configured domain, blueprints (managed and custom), projects, and environment profiles, all defined in a single configuration file:

# sagemaker.yaml --- 16 lines that deploy 114 CloudFormation resources
domains:
  domain1:
    dataAdminRole:
      id: ssm:/{{org}}/govern1/generated-role/data-admin/id
    description: SMUS Domain 1
    userAssignment: MANUAL

    tooling:
      vpcId: '{{context:vpc_id}}'
      subnetIds:
        - '{{context:private_subnet_id1}}'
        - '{{context:private_subnet_id2}}'

    groups:
      team1:
        ssoId: '{{context:team1-group-sso-id}}'
      team2:
        ssoId: '{{context:team2-group-sso-id}}'

Behind this configuration, MDAA deploys an Amazon SageMaker Unified Studio domain with dedicated KMS keys, execution and provisioning roles, and single sign-on group profiles for team access. Data producers tag and publish assets with metadata, ownership, and classification. Consumers browse a searchable catalog, see only authorized assets, and request access through a governed workflow. Cross-account and cross-business-unit data sharing flows through a subscription model, ensuring every access grant is tracked, auditable, and revocable.

Use case of MDAA: Restricting access to cardholder data using Lake Formation

AWS Lake Formation provides fine-grained access control at database and table levels, removing manual IAM policy management. MDAA deploys AWS Lake Formation with pre-configured settings that disable IAMAllowedPrincipals, the critical governance setting that ensures all permissions flow through centralized governance:

# lakeformation-settings.yaml --- 6 lines that deploy 25 CloudFormation resources
lakeFormationAdminRoles:
  - id: generated-role-id:data-admin
createCdkLFAdmin: true
createDataZoneAdminRole: true
iamAllowedPrincipalsDefault: false

That last flag is the single most important governance setting in the platform. Without it, an IAM principal with glue:GetTable can read tables in the catalog, bypassing the entire access control model. Most manual setups miss this or defer it.

With the data lake configuration, you declare roles and access policies in YAML where admins get full control, engineers get read access to curated data, extract, transform, and load (ETL) roles get scoped write access, and MDAA compiles them into the correct S3 bucket policies and Lake Formation registrations.

Use case of MDAA: Ensuring data integrity with AWS Glue Data Quality

AWS Glue Data Quality runs automated validation rulesets continuously as part of the pipeline, not as periodic batch checks. MDAA’s data quality module supports over 15 built-in rule types, from completeness and uniqueness checks to statistical thresholds and data freshness validation:

# data-quality.yaml
projectName: example-project

rulesets:
  customer-data-quality:
    description: Validate customer data completeness and uniqueness
    targetTable:
      databaseName: project:databaseName/customer-data
      tableName: customers
    ruleset:
      - ruleType: IsComplete
        column: customer_id
      - ruleType: Uniqueness
        column: email
        comparisonOperator: ">"
        threshold: 0.95
      - ruleType: RowCount
        comparisonOperator: ">"
        value: 100

Quality metrics flow into Amazon CloudWatch for real-time alerting. If anomalies are detected, automated workflows quarantine affected records and alert data engineering teams before issues reach downstream consumers.

Protecting metadata at rest: AWS Glue Data Catalog encryption

Table schemas, column names, and partition structures can reveal sensitive information about an organization’s data architecture, even without access to the underlying data. AWS Glue Catalog Encryption secures metadata at rest using AWS KMS-managed keys. MDAA configures catalog encryption by default, so schema definitions and connection passwords are encrypted from initial deployment without requiring manual key management setup. Access to catalog metadata follows the same Lake Formation governance controls applied to the data itself, so teams see only the schemas that they’re authorized to query.

Auditing every data access event: CloudTrail integration

Every data access event must be logged and attributable to a specific identity. Without a complete audit trail, demonstrating compliance during a regulatory review becomes a manual, error-prone process. AWS CloudTrail captures API-level activity across the data infrastructure, recording who accesses what data, when, and from which service. MDAA configures CloudTrail integration by default, so audit logging is active from initial deployment rather than added retroactively. Log data flows into a centralized, tamper-resistant store, giving compliance teams a single location to query access history across all business units and accounts.

Identifying sensitive data automatically: Macie integration

In large environments, sensitive information spreads across dozens of S3 buckets through pipelines, transforms, and ad hoc data drops, and self-reporting data owners consistently produce gaps. Amazon Macie uses machine learning to automatically discover and classify sensitive data in S3, surfacing findings at the object level without manual tagging. MDAA configures Macie across your S3 buckets during deployment, routing findings to Amazon EventBridge where automated workflows can alert owners or trigger remediation.

Together, these controls form a layered defense: Lake Formation governs access to cataloged data, Glue Data Quality validates integrity on arrival, and Macie identifies sensitive data that lands outside governed pipelines to reduce compliance risk.

Multi-account data mesh

MDAA provides extensive support for multi-account data mesh setups, with decentralized data ownership across business units and centralized governance. The data mesh starter kit supports cross-account data product publishing and consumption, allowing organizations to scale data sharing while maintaining consistent security and compliance controls.

Technical implementation

Ready to deploy your modern data architecture? Here are the resources to get started:

MDAA Implementation Guide provides detailed instructions for deploying all starter packages, including architecture patterns, configuration examples, security best practices, and troubleshooting guidance.

MDAA Hands-on Workshop offers step-by-step guided implementation with AWS experts. The workshop covers configuration management best practices, implementation patterns, hands-on labs with real-world scenarios, and cleanup instructions.

GitHub Repository and Documentation provide source code, module reference, and comprehensive documentation.

Organizations approach MDAA from different starting points. Some modernize existing data architectures, migrating from on-premises infrastructure or legacy cloud architectures. Others build new architectures for artificial intelligence and machine learning (AI/ML) initiatives or generative AI applications. Financial services organizations require PCI-DSS compliance from day one. Healthcare organizations need controls that can help support HIPAA. Each journey benefits from MDAA’s configuration-driven approach and embedded governance.

Conclusion

MDAA transforms data architecture development from months of manual coding to production-ready deployment. Configuration-driven infrastructure reduces development time by 40–60 percent while embedding governance from the start. The university system’s 95 percent reduction in time-to-value demonstrates the outcome: organizations deploy secure, compliant, governed data architectures in weeks rather than months.

Financial services organizations can deploy architectures to help them align with PCI-DSS compliance requirements using Lake Formation access controls, Glue Data Quality validation, SageMaker Unified Studio data discovery, comprehensive CloudTrail audit trails, and automated Macie data classification, all inherited from configuration rather than built manually.

Data architecture journeys need not follow six-month timelines with governance added incrementally. MDAA provides an alternative: describe the outcomes you want through YAML configuration, inherit pre-validated security controls, and deploy production-ready infrastructure with comprehensive governance from initial deployment.

Security and compliance is a shared responsibility between AWS and the customer. For more information, see the AWS Shared Responsibility Model.

Need help or have questions? Contact AWS ProServe for personalized guidance on selecting the right package and deployment strategy for your organization.


About the author

Sudeshna Dash

Sudeshna Dash

Sudeshna is a Data Scientist at AWS Professional Services based in Berlin, Germany. She specializes in data architecture, generative AI, and agentic AI systems on AWS. Sudeshna is a contributor to the Modern Data Architecture Accelerator (MDAA) open-source project and helps customers design and deploy governed, production-ready data and AI/ML architectures on AWS.

John Reynolds

John Reynolds is a Principal Engineer with AWS Professional Services based in Seattle, Washington. He leads the architecture and development of Modern Data Architecture Accelerator (MDAA), focusing on turning proven delivery patterns into reusable, production-ready foundations that customers can adopt and extend at scale.

How Buildkite Operates Test Analytics at Massive Scale with Amazon MSK and Amazon Managed Service for Apache Flink

Post Syndicated from James Hill original https://aws.amazon.com/blogs/big-data/how-buildkite-operates-test-analytics-at-massive-scale-with-amazon-msk-and-amazon-managed-service-for-apache-flink/

When engineering teams at Slack, Reddit, Canva, Airbnb, Shopify, and Uber need to ship code with confidence, they rely on Buildkite. As a CI/CD platform, Buildkite orchestrates complex build, test, and deployment pipelines for some of the most demanding engineering organizations in the world. It handles everything from routine code commits to artificial intelligence (AI) model-training workloads, processing over 50 billion requests per month.

At the heart of Buildkite’s test orchestration portfolio is Test Engine, a specialized analytics product designed to help engineering teams understand and optimize their test suites at scale. Test Engine aggregates results across thousands of builds, flags flaky tests, runs parallel test execution across machine fleets, and delivers interactive analytics on test execution data. It supports arbitrary metadata tagging for dimensions like instance type, architecture, language version, cloud provider, and feature flags.

The challenge? Delivering all of this in real time, across multiple enterprise tenants, at a volume that would stress even the most robust data infrastructure. In this post, we explore how Buildkite uses Amazon Managed Streaming for Apache Kafka (Amazon MSK) and Amazon Managed Service for Apache Flink to power Test Engine’s streaming-first analytics architecture at scale.

The problem: When scale breaks traditional architectures

Buildkite’s Test Engine must ingest and serve analytics on test telemetry from thousands of distributed pipelines simultaneously, for multiple enterprise customers. The scale is unforgiving: 50 billion test executions per month, 500K events per second at peak ingestion, and webhook payloads reaching 21 MB.

The architectural evolution and its limits

The original Rails and PostgreSQL stack couldn’t sustain this growth. In 2024, the team re-architected around a distributed streaming layer, a stateful stream processor for pre-aggregations, and multiple specialized stores: a key-value store for fast lookups, a relational database for pre-computed aggregates, and an open table format (Iceberg) with a distributed query engine (Trino) for flexible querying.

Yet the core tension remained unsolved. Enterprise customers demanded interactive, arbitrary slicing of billions of records across high-cardinality dimensions, not canned reports. The stream processor couldn’t handle ad hoc aggregations at query time. The key-value store was blind to analytical queries. The distributed query engine offered flexibility but was too slow for interactive use.

The result was a system that was expensive and operationally complex. It included nine relational database clusters, sprawling ETL pipelines, and 24/7 pre-aggregation jobs running regardless of demand. It still couldn’t deliver the one thing customers needed most: fast, flexible, interactive analytics at scale.

Architecture and implementation: MSK and Amazon Managed Service for Apache Flink as the streaming backbone

The solution Buildkite arrived at centers on Amazon Managed Streaming for Apache Kafka (Amazon MSK) and Amazon Managed Service for Apache Flink as the real-time data streaming and processing layers, decoupling high-throughput ingestion from downstream analytics.

The data pipeline

The following diagram shows the end-to-end data flow from CI/CD agents through Amazon MSK and Amazon Managed Service for Apache Flink to the analytics layer.

Architecture diagram showing the Buildkite data pipeline from CI/CD agents through Amazon MSK and Amazon Managed Service for Apache Flink to ClickHouse analytics

Amazon MSK sits at the critical junction between data producers (the distributed CI/CD agents and test collectors running across customer infrastructure) and the downstream processing and analytics layers. Amazon Managed Service for Apache Flink then transforms those raw event streams into enriched, queryable data before it reaches the analytics store.

High-throughput ingestion from CI/CD pipelines

Amazon MSK’s role begins at ingestion. Test collectors embedded in CI/CD pipelines publish test execution events directly to Kafka topics. The existing Amazon MSK cluster handles between 5 MB/sec and 100 MB/sec of inbound data under normal operating conditions. The architecture is designed to absorb the significant variance inherent in CI/CD workloads, where pipeline activity is bursty and correlated with engineering team working hours across global time zones.

When the Buildkite project was initiated, MSK Express Brokers were not yet available, leading the team to adopt MSK Tiered Storage as the primary mechanism for scaling and recovery. With MSK Express Brokers now generally available, the team is evaluating a migration of its most critical log ingestion workload, which sustains up to 1 GB/s at peak ingestion. MSK Express Brokers bring automatic storage scaling with zero storage management overhead, up to 20x faster scaling and 90% faster broker recovery, 3x higher per-broker throughput, 5x more partitions per broker, and built-in Intelligent Rebalancing.

Real-time stream processing with Amazon Managed Service for Apache Flink

Sitting between Amazon MSK and the analytics layer, Amazon Managed Service for Apache Flink acts as the stateful stream processing engine that transforms raw event streams before they reach downstream systems. Buildkite selected Flink for its exactly-once processing, mature stateful computation model, and deep Kafka integration. Handling sustained peaks of over 25,000 events per second, Amazon Managed Service for Apache Flink eliminates the operational overhead of cluster provisioning, version upgrades, checkpointing, and job recovery. This frees engineering teams to focus on application logic.

Amazon Managed Service for Apache Flink powers key stateful processing tasks, including flaky test detection through time-windowed pattern matching, enriching execution events with pipeline and customer metadata, and routing processed data to downstream systems such as ClickHouse for analytics, PostgreSQL for operational workloads, and Amazon Simple Storage Service (Amazon S3) for long-term archival.

Reliability and fault tolerance

Amazon MSK’s three-replica configuration ensures that no single broker failure can cause data loss or ingestion interruption. Combined with flexible data retention, the architecture provides a meaningful replay window. If a downstream consumer (Amazon Managed Service for Apache Flink, ClickHouse, or another service) experiences an outage, it can resume processing from its last committed offset without data loss.

During the migration to the current architecture, Buildkite employed a dual-write strategy: simultaneously writing to both the existing PostgreSQL pipeline and the new Amazon MSK/ClickHouse path. This approach allowed the team to validate data consistency and gradually shift traffic without risking customer-facing disruption. This pattern speaks to the operational maturity Amazon MSK provides.

Operational efficiency gains

The shift to a streaming-first architecture, combined with the downstream simplification of the analytics engine, produced significant operational improvements:

  • Flink workloads reduced by 60%+: Eliminating pre-aggregation jobs that ran continuously regardless of demand.
  • Key/value store completely retired: Amazon MSK’s buffering capability, combined with ClickHouse’s query performance, eliminated the need for a separate fast-lookup store.
  • PostgreSQL capacity cut in half: Nine separate database clusters consolidated and right-sized.
  • Thousands of lines of application code deleted: Simpler architecture means less ETL code, fewer failure modes, and faster onboarding for new engineers.

Platform performance at a glance

Metric Value
Monthly test executions (for test engine platform) 50 billion (4x growth from 3B)
Sustained peak ingestion 500K events/second
Total records in analytics store 200 billion
Log ingestion requests 70,000+ per second
Peak webhook throughput 1.7 GB/second
MSK inbound throughput range 5 MB/sec – 100 MB/sec

Business and developer impact

The technical architecture ultimately exists to serve one purpose: helping developers ship better software faster. The streaming-first architecture built on Amazon MSK and Amazon Managed Service for Apache Flink delivers on that promise across four dimensions.

On-demand analytics replaced pre-computed reports. Customers can now interactively slice and dice 70 billion records across arbitrary metadata dimensions. They get answers to queries like “Show me P50 test durations by instance type and architecture for the last 30 days” in seconds, not hours. Real-time log streaming through the “live tail” feature means developers no longer wait for a build to complete before diagnosing failures. At 25,000 events per second, this experience scales across thousands of concurrent enterprise pipelines without degradation.

Smarter test intelligence comes from Amazon Managed Service for Apache Flink’s stateful flaky test detection: when a test begins exhibiting intermittent failure patterns, Amazon Managed Service for Apache Flink identifies it as it happens, not after the fact. This is what separates a proactive analytics platform from a reactive one. It requires publishing data to Kafka, processing with Flink, and letting ClickHouse handle the complex read requests.

Conclusion: Streaming as a strategic foundation

Buildkite’s journey from a Rails/Postgres monolith to a streaming-first analytics platform reflects a pattern increasingly common among enterprise SaaS companies: a reliable, high-throughput streaming and processing layer is not an optimization. It is a prerequisite for operating at scale.

Amazon MSK and Amazon Managed Service for Apache Flink form the backbone that helps Buildkite ingest 50 billion test executions per month, serve real-time interactive analytics to enterprise customers, and do so at lower cost than the more complex architecture it replaced. Amazon MSK handles durable, elastic event buffering. Amazon Managed Service for Apache Flink transforms raw streams into enriched, queryable data. Together they absorb the operational complexity that would otherwise consume engineering capacity.

For platform engineers evaluating streaming infrastructure for multi-tenant SaaS workloads, the signal is clear: invest in the streaming backbone early, and let managed services handle the operational complexity.

To learn more about Amazon MSK and Amazon Managed Service for Apache Flink, visit aws.amazon.com/msk and aws.amazon.com/managed-service-apache-flink.


About the authors

James Hill

James Hill

James has been building and scaling software systems for more than 25 years, from early web applications to platforms that now process millions of builds every day. Starting his career as a software engineer, James has led teams across Australia, the UK, and globally, solving problems in performance, reliability, and delivery speed at massive scale. Today, he works with some of the world’s largest engineering organizations to help them ship faster and with greater confidence, drawing on deep, hands-on experience in both engineering and product leadership. James is passionate about turning testing from a bottleneck into a feedback engine that accelerates learning across an organization.

Mitch James

Mitch James

Mitch is a Brand and Marketing Strategist with deep expertise crafting end-to-end brand experiences and fostering engaged communities around technical tooling. He brings 15+ years of Brand, Design, and Marketing leadership across devtools, consumer product, and B2B enterprise. Previously, Mitch has built and led creative teams at Adobe, IBM, Salesforce, George P Johnson, Wunderman Thompson, and VML. Today, he leads global marketing and design for Buildkite, working with engineering teams who set the pace at the frontier of software delivery.

Masudur Rahaman Sayem

Masudur Rahaman Sayem

Masudur is a Streaming Data Architect at AWS with over 25 years of experience in the IT industry. He collaborates with AWS customers worldwide to architect and implement data streaming solutions that address complex business challenges. As an expert in distributed computing, Sayem specializes in designing large-scale distributed systems architecture for maximum performance and scalability. He has a keen interest and passion for distributed architecture, which he applies to designing production-ready solutions at internet scale.

Miranda Li

Miranda Li

Miranda is a Senior Solutions Architect at AWS, specializing in Independent Software Vendor (ISV) and cloud-native architectures. With four years dedicated to helping software partners innovate and scale on AWS, she focuses on helping ISVs build and optimize their solutions for the cloud. She brings deep technical expertise in cloud infrastructure and data analytics, with a strong focus on supporting technical customers in areas such as Infrastructure as a Service (IaaS), network architecture, and security. Outside of work, she is an avid badminton player and enjoys staying active through jogging and outdoor adventures.

How to build a cross-Region resilience for Amazon OpenSearch Service with Amazon MSK

Post Syndicated from Sriharsha Subramanya Begolli original https://aws.amazon.com/blogs/big-data/how-to-build-a-cross-region-resilience-for-amazon-opensearch-service-with-amazon-msk/

Cross-Region resilience for Amazon OpenSearch Service has historically been a complex challenge, relying on S3-based snapshots or cross-cluster replication that demand intricate manual failover procedures often resulting in hours of downtime, data inconsistencies, and significant lag during outages, or other operational disruptions. To overcome these limitations and help businesses stay focused on their core objectives, we’ve developed a solution that automatically maintains synchronized data across AWS Regions while supporting active-active operations in both AWS Regions.

AWS offers two OpenSearch offerings, namely Amazon OpenSearch Service, a managed cluster-based service where you provision and manage OpenSearch domains (nodes, storage, scaling), and Amazon OpenSearch Serverless, a serverless option where AWS automatically manages infrastructure and scaling and you create collections for your search or analytics workloads. OpenSearch Service provides high availability (HA) within an AWS Region through its Multi-AZ deployment model and provides Regional resiliency with cross-cluster replication. Amazon Managed Streaming for Apache Kafka (Amazon MSK) Replicator is an Amazon MSK feature that you can use to reliably replicate data across Amazon MSK clusters in different or the same AWS Region.

In this post, we outline the solution that provides cross-Region resiliency without needing to reestablish relationships during a fail-back, using an active-active replication model with Amazon OpenSearch Ingestion (OSI) and Amazon Managed Streaming for Apache Kafka (Amazon MSK). This solution applies to both OpenSearch Service managed clusters and Amazon OpenSearch Serverless collections. We use Amazon OpenSearch Serverless as an example for the configurations in this post.

Solution overview

In this solution we use Amazon MSK Replicator for bidirectional cross-Region data replication, with OSI pipelines to index data into Amazon OpenSearch Serverless collections in each AWS Region. While the S3 based approach serves the purpose, Amazon MSK Replicator provides near real-time replication with identical topic naming, which supports active-active operations. Amazon MSK Replicator provides automatic loop prevention and consumer group offset synchronization, enabling seamless cross-Region failover. You can find the code for the entire solution in the GitHub repo.

Your architecture will follow a Regional-first approach where data sources write to a local Amazon MSK cluster within their AWS Region. In this sample deployment, an AWS Lambda function serves as the producer, streaming data into the MSK cluster. OSI pipelines consume the incoming data from the local MSK cluster and persist it to an Amazon OpenSearch Serverless collection within the same AWS Region. To achieve cross-Region data synchronization, Amazon MSK Replicator facilitates bidirectional replication between the Amazon MSK clusters, preserving the same topic names across both environments. This design validates that Amazon OpenSearch Serverless collections in each AWS Region maintain identical datasets, provides low-latency search capabilities and high availability for globally distributed workloads.
Prerequisites

Deploy the AWS Cloudformation template to install the prerequisites. The solution has the following prerequisite steps:

  1. Set up Amazon Virtual Private Cloud (Amazon VPC) infrastructure in both Regions
    1. Create Amazon VPCs with private subnets in at least two or three Availability Zones for high availability at the AWS Region level
    2. Configure Network Address Translation (NAT) Gateways for outbound internet access from private subnets
    3. Use non-overlapping CIDR blocks
  2. Establish Amazon OpenSearch Serverless collections in both AWS Regions
  3. Create Amazon OpenSearch Serverless Collections for log analytics
  4. Configure encryption, network, and data access policies
  5. Create Amazon VPC endpoints for private access
  6. Configure MSK clusters in both AWS Regions
  7. Enable AWS Identity and Access Management (IAM) authentication (SASL/IAM)
  8. Enable Multi-VPC connectivity (required for Amazon MSK Replicator and OSI)
  9. Configure MSK cluster policies to allow kafka.amazonaws.com and osis-pipelines.amazonaws.com service principals
  10. Configure IAM permissions for pipeline and replication access
  11. Create IAM roles for the OSI pipelines with permissions to access Amazon Managed Streaming for Apache Kafka and Amazon OpenSearch Serverless.
  12. Create IAM roles for the Amazon MSK Replicator with permissions for cross-Region access to Amazon Managed Streaming for Apache Kafka clusters.

This AWS CloudFormation template helps you in deploying all of the required configurations with primary AWS Region as us-east-1 and secondary AWS Region as us-west-2.

The following snippets shows the configuration for the OSI pipeline, which writes data from Amazon MSK to Amazon OpenSearch Serverless. The OSI pipeline uses MSK as a source with IAM authentication.

version: "2"
kafka-pipeline:
source:
kafka:
acknowledgments: true
topics:
- name: "opensearch-data"
group_id: "osi-consumer-group-primary"
aws:
msk:
arn: "arn:aws:kafka:us-east-1:<aws-acccount-id>:cluster/production-msk-primary/CLUSTER_ID"
region: "us-east-1"
sts_role_arn: "arn:aws:iam::<aws-acccount-id>:role/production-osi-pipeline-primary-role"
sink:
- opensearch:
hosts:
- "https://<OPENSEARCH_SERVERLESS_COLLECTION_ID>.us-east-1.aoss.amazonaws.com"
index: "application-logs-${yyyy.MM.dd}"
aws:
serverless: true
region: "us-east-1"
sts_role_arn: "arn:aws:iam::<aws-acccount-id>:role/production-osi-pipeline-primary-role"
dlq:
s3:
bucket: "production-opensearch-dlq-us-east-1"
region: "us-east-1"
sts_role_arn: "arn:aws:iam::<aws-acccount-id>:role/production-osi-pipeline-primary-role"

The OSI pipeline IAM Role has the required permission for Amazon MSK and Amazon OpenSearch Serverless to consume message data from the source and write data to the destination. For true active-active replication, sample deploys two Amazon MSK Replicators in each AWS Region. Each Amazon MSK cluster requires cluster policy to allow Amazon MSK Replicator and OSI to connect. To validate the bidirectional replication, the solution uses AWS Lambda functions to produce test messages to both Amazon MSK clusters.

When an application generates an event, it first publishes the message to an Apache Kafka topic in the Regional streaming cluster powered by Amazon Managed Streaming for Apache Kafka. In this sample deployment, an AWS Lambda function simulates application activity by producing events into the topic. These events are durably stored in the Apache Kafka partitions, providing a reliable buffer between producers and downstream consumers. An ingestion pipeline built using Amazon OpenSearch Ingestion continuously reads the event stream from the Apache Kafka topic and prepares the data for indexing. The pipeline then indexes the processed events into a collection in Amazon OpenSearch Serverless, making the data searchable in near real time.
At the same time, Amazon MSK Replicator replicates the Apache Kafka topic to a peer Amazon MSK cluster in a secondary AWS Region while preserving the topic structure. This makes the same event stream available in the secondary AWS Region without requiring changes to downstream consumers. An OpenSearch Ingestion pipeline in the secondary AWS Region consumes the replicated topic and indexes the events into its local OpenSearch Serverless collection. As events continue to flow through the system, both AWS Regions maintain synchronized datasets that can be queried independently. This architecture enables low-latency Regional search while maintaining a resilient, cross-Region copy of the indexed data.

Failover scenario and considerations

You can failover your application to the Amazon OpenSearch Serverless collection in the other AWS Region and continue operations without interruption. The data present before the impairment is available in both collections. Upon recovery, Amazon MSK Replicator and OSI pipelines automatically resume operations without manual intervention. Data that you write to the healthy AWS Region during the impairment is automatically backfilled to the recovered AWS Region. For detailed step-by-step guidance, see disaster recovery section in GitHub repo.

When using Amazon MSK Replicator, be aware that cross-Region data transfer incurs additional costs. To help verify reliability, configure Dead Letter Queues (DLQ) for OSI pipelines to capture failed document ingestion. Additionally, monitor essential Amazon CloudWatch metrics including ReplicationLatency for tracking lag between clusters, DocumentsFailed for identifying ingestion issues, and MessagesInPerSec for observing message throughput.

Persistent buffering in OSI provides a built-in safety net that prevents data loss when data producers send information faster than your OpenSearch cluster can process it, removing the need to provision and manage separate buffering infrastructure. By using managed storage across multiple Availability Zones, this feature enhances data durability while dynamically allocating OpenSearch Compute Units (OCUs) for both buffering and data processing, which incurs additional costs. Persistent buffering isn’t enabled by default. Without it, the OSI pipeline relies on an in-memory buffer, which is volatile and has limited capacity for storing incoming data before processing.

Conclusion

In this post, we showed you how to achieve cross-Regional resiliency for Amazon OpenSearch Serverless and OpenSearch Service managed clusters. In our experiments, most writes of a few KBs of data completed within one to a few seconds between the two chosen AWS Regions. Replication lag between the AWS Regions depends on network delay between chosen Regions and the settings configured on Amazon Opensearch Ingestion (OSI) pipeline.

Refer to AWS Service Level Agreements (SLAs) and Amazon Opensearch Ingestion (OSI) for more details. You can also achieve active-passive replication for OpenSearch using OSI and Amazon Simple Storage Service (Amazon S3) as mentioned in another post Achieve cross-Region resilience with Amazon OpenSearch Ingestion.


About the authors

Sriharsha Subramanya Begolli works as a Senior Solutions Architect with AWS, based in Bengaluru, India. His primary focus is assisting large enterprise customers in modernising their applications and developing cloud-based systems to meet their business objectives. His expertise lies in the domains of data, analytics and generative AI.

Qais Poonawala is a Senior Technical Account Manager at AWS Enterprise Support, India, who specializes in Cloud Operations and Security while helping customers architect highly scalable, resilient, and secure solutions. With extensive experience in enabling enterprise customers across AWS services, he has a passion for solving complex challenges and developing solutions around Security, Cloud Operations, and GenAI.

Jay Jothi is a Senior Technical Account Manager based in Chennai, India, where he supports major enterprise customers in maximizing the benefits of cloud technology. With extensive experience in the financial services industry and a specialization in Cloud Operations, he focuses on helping financial clients manage data efficiently, derive actionable insights using GenAI, and deliver cost-effective solutions.

Migrating TLS Clients managed by third-party Certificate Authorities from self-managed Apache Kafka to Amazon MSK

Post Syndicated from Ali Alemi original https://aws.amazon.com/blogs/big-data/migrating-tls-clients-managed-by-third-party-certificate-authorities-from-self-managed-apache-kafka-to-amazon-msk/

Amazon Managed Streaming for Apache Kafka (Amazon MSK) is a fully managed streaming data service that handles Apache Kafka infrastructure and operations, so developers and DevOps managers can run Apache Kafka applications on AWS. Migrating to Amazon MSK requires no application code changes because Amazon MSK uses fully open source Apache Kafka, allowing existing applications and tools to work seamlessly. Amazon MSK with Express brokers streamlines Kafka management by providing up to 3x more throughput, 20x faster scaling, and 180x faster recovery with virtually unlimited storage, delivering resiliency and elasticity for mission-critical workloads.

Amazon MSK supports multiple authentication methods to secure client connections to Kafka clusters. These methods include:

When customers manage their own Kafka clusters and adopt mTLS, they typically rely on a third-party managed certificate authority (CA) to sign and verify both client and server certificates. This establishes a trust relationship where the CA acts as the trusted intermediary that validates the identity of both parties in the communication. When customers migrate their workloads to Amazon MSK, they must make sure that client certificates are signed by a CA that’s recognized and trusted by the MSK cluster. Amazon MSK recommends customers to use AWS Private Certificate Authority to create a private CA within AWS that MSK trusts. The migration path typically requires customers to either:

  1. Generate new client certificates signed by an AWS Private CA that Amazon MSK recognizes, or
  2. Establish a certificate chain where their existing third-party CA is subordinate to or trusted by an AWS-managed CA

In this post, we provide an approach to reuse your existing client certificates without reissuing them through AWS Certificate Manager (ACM) Private Certificate Authority. This solution enables an accelerated migration path by using your current third-party CA infrastructure. This removes the complexity and operational overhead of certificate re-issuance while maintaining the security posture that you’ve established with your existing mTLS implementation.

Solution overview

This approach involves four key steps to reuse your existing client certificates when migrating to Amazon MSK:

1. Create an Intermediate Certificate Using Your Third-Party CA

First, you generate an intermediate certificate authority (CA) certificate using your existing third-party CA infrastructure. This intermediate certificate acts as a bridge between your current certificate management system and AWS.

2. Import the Intermediate Certificate into AWS Certificate Manager as a Private CA

Next, you import this intermediate certificate into AWS Certificate Manager (ACM) as a Private Certificate Authority (PCA). This step establishes the intermediate CA within the AWS environment, making it recognizable to AWS services.

3. Integrate Amazon MSK with the PCA created from your Intermediate Certificate

You then configure your Amazon MSK cluster to use the ACM Private CA that contains your imported intermediate certificate. This integration enables Amazon MSK to recognize and trust certificates signed by your certificate authority.

4. Establish trust through common Certificate Authority

This approach works because both the AWS Private CA and your existing client certificates share the same root of trust—they’re both signed by your third-party CA. When Amazon MSK validates client certificates, it can trace the certificate chain back through the intermediate certificate in AWS Private CA to your trusted third-party CA, establishing a complete chain of trust without requiring certificate reissuance.This solution maintains your existing security architecture while enabling seamless migration to Amazon MSK, so your clients can continue using their current certificates without interruption.

Figure 1: Architecture diagram showing the integration of third-party Certificate Authority with Amazon MSK through AWS Certificate Manager Private CA

Implementation steps

In real-world scenarios, you already have a certificate authority that has issued certificates for your clients. For the purpose of this post, we use a code sample to create a self-signed certificate authority (using OpenSSL) to demonstrate the implementation steps. If you already have an existing certificate authority, you don’t need to create a root CA. You can generate an intermediate CA (Step 2) using your third-party CA and continue following the steps from where you import the intermediate CA certificate into AWS ACM as a Private Certificate Authority.

Step 1: Create a root Certificate Authority using OpenSSL

Cloning the repository

To clone the repository, complete the following steps:

  1. Clone the repository using the following command:

git clone https://github.com/aws-samples/msk-third-party-mtls

  1. Change to the repository’s root directory:

cd ./msk-third-party-mtls/openssl

  1. Run the setup script:

make the script executable first:

chmod +x *.sh
./setup-ca.sh

You will be prompted to set up a password for the private key and the certificate. Here is an example of an output

Step 2: Create an intermediate CA for AWS ACM

  1. In the AWS Private CA console, create a subordinate CA.

  1. Enter distinguished name information matching your organization, Key algorithm and Create CA.
  2. From the Actions menu, select Install CA certificate.
  3. Download the Certificate Signing Request (CSR) file provided by AWS Private CA.

  1. Download the CSR file to your local directory (“certs”) as “CSR.pem”.

  1. Sign the ACM PCA issued CSR with your Root CA using the provided ./sign-acm-ca.sh in the code example.

Note: AWS Private CA retains the private key internally. You only sign their CSR and import the resulting certificate back to the AWS Private CA.

Step 3: Import signed certificate to AWS ACM Private CA

  1. Go back to the AWS ACM console.
  2. Select the CA that you created and select Install CA certificate.

  1. Select External private CA as CA type.

Importing the certificate into AWS Certificate Manager

Open both files in a text editor:

  • acm-subordinate-ca-cert.pem
  • acm-ca-chain.pem

Do the following in the Certificate body field in AWS ACM:

  • Copy the entire content from the acm-subordinate-ca-cert.pem file and paste it into the text box.
  • Open the acm-ca-chain.pem file.
  • This file contains one certificate (The root CA certificate)
  • Do the following in the Certificate chain field in AWS ACM:
  • Copy the root CA certificate portion and paste it into the text box

Important: The certificate chain shouldn’t include the subordinate CA certificate itself—only the certificates above it in the chain (the root CA).

  • Choose Confirm and install to complete the process.

You should see the AWS Private CA turns into active state.

Step 4: Configure your MSK cluster for Mutual TLS authentication

  1. Select your MSK cluster, go to Properties and edit the Security settings.
  2. Select TLS client authentication through AWS Certificate Manager (ACM) as the access control method and choose the Subordinate CA that you created earlier. Then choose Save changes.

Step 5: Test your client

Run the certificate generation script

Execute the following command, replacing <client-name> with a descriptive name for your client (this will be used in the certificate filename):./generate-client-cert.sh <client-name>

Example:

./generate-client-cert.sh kafka-admin

Enter distinguished name information

When prompted, enter the distinguished name (DN) options. These should match your root CA settings except for the Common Name (CN):

  • Country (C): Match your root CA (for example, US)
  • State (ST): Match your root CA (for example, State)
  • Organization (O): Match your root CA (for example, Anycompany)
  • Organizational Unit (OU): Match your root CA (for example, IT)
  • Common Name (CN): Use a client-specific identifier (for example, kafka-admin or client)

Verify certificate files

After the certificate is generated, verify that the files were created successfully by running:ls ~/ca/certsYou should see files with your client name, including:

  • <client-name>.key (private key)
  • <client-name>.crt (certificate)
  • <client-name>.p12 (PKCS12 keystore)

Create Kafka client properties file

Create a new properties file for your Kafka client (for example, kafka-tls-client.properties) based on the provided kafka-admin-ssl.properties example file. Update the file paths to reference your newly generated client certificate files.

Example configuration:

security.protocol=SSL
ssl.keystore.location=/path/to/<client-name>.p12
ssl.keystore.password=your-keystore-password
ssl.key.password=your-key-password #omit if you didn’t set key password
ssl.keystore.alias=your-private-key-alias

Step 6: Testing the Kafka client connection

To test the Kafka client connection, do the following.

Set environment variables

First, set the required environment variables for your Kafka installation and MSK cluster:

export KAFKA_HOME=/home/ec2-user/kafka
export BOOTSTRAP_SERVERS=<your-msk-bootstrap-servers>

Note: Replace <your-msk-bootstrap-servers> with your actual Amazon MSK cluster bootstrap server endpoints (for example, b-1.mycluster.abc123.kafka.us-east-1.amazonaws.com:9094,b-2.mycluster.abc123.kafka.us-east-1.amazonaws.com:9094)

Run the Kafka list topics command

Execute the following command to verify that your client can successfully connect to Amazon MSK using mutual TLS authentication:

$KAFKA_HOME/bin/kafka-topics.sh \
  --bootstrap-server $BOOTSTRAP_SERVERS \
  --list \
  --command-config kafka-tls-client.properties

What this test does:

  • Connects to your Amazon MSK cluster using the TLS configuration in your properties file
  • Authenticates using your client certificate
  • Lists all available Kafka topics

Expected result: If successful, you should see a list of topics in your Kafka cluster (or an empty list if no topics exist yet).

If the connection fails, check:

  • Your bootstrap server endpoints are correct
  • You imported the private key, and certificate chain to your keystore
  • The paths in your properties file point to the correct keystore and truststore files
  • Your client certificate was properly imported
  • Your Amazon MSK cluster security settings allow TLS client authentication
  • Your Amazon MSK cluster references correct PCA ARN in AWS ACM

Troubleshooting

Enable debug mode to verify certificate handshake

To troubleshoot certificate issues and verify which certificates are involved in the TLS handshake, enable Java SSL debug mode:

export KAFKA_OPTS="-Djavax.net.debug=ssl:handshake:verbose"
$KAFKA_HOME/bin/kafka-topics.sh \
  --bootstrap-server $BOOTSTRAP_SERVERS \
  --list \
  --command-config kafka-tls-client.properties

What this debug mode shows:

  • The complete TLS handshake process
  • Which certificates are being presented by both client and server
  • The certificate chain validation steps
  • Which certificate from your truststore is being used for authentication

When this is helpful:

  • When you have multiple certificates in your truststore and need to identify which one is being used
  • When troubleshooting certificate chain validation issues
  • When verifying that the correct client certificate is being presented during authentication
  • When diagnosing certificate mismatch or trust issues

Reading the debug output:

Look for lines containing:

  • ***Certificate chain – Shows the certificates being presented
  • Found trusted certificate – Indicates which certificate in your truststore matched
  • Cert path validation – Shows the certificate chain validation process

To disable debug mode after troubleshooting, simply unset the environment variable:

unset KAFKA_OPTS

Conclusion

This post presents a solution for migrating TLS clients from self-managed Apache Kafka to Amazon MSK while reusing existing third-party CA-signed certificates. The approach removes the need for certificate reissuance by instead creating an intermediate CA from the existing third-party CA, importing it into AWS Certificate Manager as a Private CA, and integrating it with Amazon MSK. This maintains the established chain of trust through the common certificate authority, enabling seamless migration without operational disruption while preserving the existing security architecture and mTLS implementation. To read more about the Amazon MSK security model, see Security in Amazon MSK.


About the authors

Author Ali Alemi

“Ali Alemi”

“Ali” is a Principal Streaming Solutions Architect at AWS. Ali advises AWS customers with architectural best practices and helps them design real-time analytics data systems which are reliable, secure, efficient, and cost-effective. Prior to joining AWS, Ali supported several public sector customers and AWS consulting partners in their application modernization journey and migration to the Cloud.

“Swapna Bandla”

“Swapna” is a Senior Streaming Solutions Architect at AWS. With a deep understanding of real-time data processing and analytics, she partners with customers to architect scalable, cloud-native solutions that align with AWS Well-Architected best practices. Swapna is passionate about helping organizations unlock the full potential of their data to drive business value. Beyond her professional pursuits, she cherishes quality time with her family.

Configure a custom domain name for your Amazon MSK cluster enabled with IAM authentication

Post Syndicated from Mazrim Mehrtens original https://aws.amazon.com/blogs/big-data/configure-a-custom-domain-name-for-your-amazon-msk-cluster-enabled-with-iam-authentication/

Most Amazon Managed Streaming for Apache Kafka (Amazon MSK) customers are simplifying and standardizing access control to Kafka resources using AWS Identity and Access Management (IAM) authentication. This adoption is also accelerated as Amazon MSK now supports IAM authentication in popular languages including Java, Python, Go, JavaScript, and .NET.

In the first part of Configure a custom domain name for your Amazon MSK cluster, we discussed about why custom domain names are important and provided details on how to configure a custom domain name in Amazon MSK when using SASL_SCRAM authentication. In this post, we discuss how to configure a custom domain name in Amazon MSK when using IAM authentication. We recommend you read the first part of this blog as it captures solution details implementation steps.

Solution overview

IAM authentication for Amazon MSK uses TLS to encrypt the Kafka protocol traffic between the client and Kafka broker. To use a custom domain name, the Kafka broker needs to present a server certificate that matches the custom domain name. To achieve this, this solution uses an Network Load Balancers (NLBs) with Amazon Certificate Manager to provide a custom certificate on behalf of the MSK brokers, and a Route 53 Private Hosted Zone to provide DNS for the custom domain name.

The following diagram shows all components used by the solution.

Architecture showing configuration of custom domain name with Amazon MSK

Certificate management

For clients to perform TLS communication with the MSK cluster the cluster needs to provide a certificate with hostnames matching the custom domain name. This solution uses a certificate in AWS Certificate Manager (ACM) signed with a Private Certificate Authority (PCA) for TLS with the custom domain name. This solution uses a certificate with bootstrap.example.com as the Common Name (CN) so that the certificate is valid for the bootstrap address, and Subject Alternative Names (SANs) are set for all broker DNS names (such as b-1.example.com). Since this solution uses a private certificate authority, the CA chain must be imported into the client trust stores.

This solution works with any server certificate, whether certificates are signed by a public or private Certificate Authority (CA). You can import existing certificates into ACM to be used with this solution. Certificates must provide a common name and/or subject alternative names that match the bootstrap DNS address as well as the individual broker DNS addresses. If the certificate is issued by a private CA, clients need to import the root and intermediate CA certificates to the client trust store. If the certificate is issued by a public CA, the root and intermediate CA certificates will be in the default trust store.

Network Load Balancer

The NLB provides the ability to use a TLS listener. The ACM certificate is associated with the listeners and enables TLS negotiation between the client and the NLB. The NLB performs a separate TLS negotiation between itself and the MSK brokers. In addition to the above architecture, this solution also allows using AWS Private Link to connect the cluster to external VPCs. This allows secure access to MSK between VPCs while using a custom domain name.

The following diagram illustrates the NLB port and target configuration. A TLS listener with port 9000 is used for bootstrap connections with all MSK brokers set as targets. IAM authentication is configured to run on port 9098 of the MSK brokers using a TLS target type. A TLS listener port is used to represent each broker in the MSK cluster. In this post, there are three brokers in the MSK cluster starting with port 9001, representing broker 1 and up to port 9003, representing broker 3.

Target Group mapping in NLB

Domain Name System (DNS)

For the client to resolve DNS queries for the custom domain, we use an Amazon Route 53 private hosted zone to host the DNS records, and associate it with the client’s VPC to enable DNS resolution from the Route 53 VPC resolver. This solution uses a private MSK cluster and private DNS. For publicly accessible MSK clusters a public NLB and DNS provider such as a Route53 public hosted zone can be used.

Amazon MSK

Finally, each broker needs to have its advertised listeners configuration (advertised.listeners) updated to match the custom domain name and NLB ports. Advertised listeners is a configuration option used by Kafka clients to connect to the brokers. By default, an advertised listener is not set. Once set, Kafka clients use the advertised listener instead of listeners to obtain the connection information for brokers. MSK brokers use the listener configuration to tell clients the DNS names and ports to use to connect to the individual brokers for each authentication type enabled. Advertised listeners are unique to each broker; and the cluster won’t start if multiple brokers have the same advertised listener address. For this reason, this solution uses a unique custom DNS name for each broker (such as, b-1.example.com).

Solution Deployment

To deploy the solution, use the CloudFormation template from the GitHub repository.

This template deploys a VPC, NLB, PCA, ACM certificate, MSK cluster, and an Amazon EC2 instance for cluster connectivity. The EC2 instance includes a script to handle updating the broker advertised.listeners settings to match the custom domain name. For more information on deploying a CloudFormation template, refer to Create a stack from the CloudFormation console.

After deploying the CloudFormation template, run the script to update advertised listeners as follows:

  1. Retrieve the MSKClusterARN and CertificateAuthorityARN from the CloudFormation outputs for your stack as they will be used in subsequent steps.
  2. Navigate to the EC2 console and identify the KafkaClientInstance. Choose Connect to connect to the instance using AWS Systems Manager Session Manager.
  3. Session Manager starts a session in shell. Start a bash session with the command:
    bash -l

  4. The Kafka client SDKs have already been installed in the EC2 instance. You can update the advertised.listeners configuration as follows, replacing CLUSTER_ARN with the ARN of your MSK cluster retrieved from CloudFormation in step 1:
    ./update_advertised_listeners.sh --region us-east-1 --cluster-arn CLUSTER_ARN

    Note that once this script completes, the brokers will have new advertised listeners configurations. Connections using the standard IAM address for the MSK service will not work until we complete the next steps, as the brokers will redirect connections over this address back to the custom domain name and TLS will fail.

  5. Next, we need to create a truststore with the certificate for our AWS Private Certificate Authority (PCA) to allow TLS with the NLB. In the following command, replace PCA_ARN with the ARN of the PCA retrieved from CloudFormation in step 1:
    We’re using the default Java truststore which uses the password changeit.When asked “Trust this certificate?” enter “yes”.
    export PCA_ARN=<<PCA_ARN>>
    export REGION=<<REGION>>
    
    cp /etc/pki/java/cacerts . && chmod 600 cacerts
    aws acm-pca get-certificate-authority-certificate --certificate-authority-arn $PCA_ARN --region $REGION | jq -r '.Certificate' > pca.pem
    keytool -import -file pca.pem -alias AWSPCA -keystore cacerts

  6. Create a new properties file to allow IAM authentication with our custom truststore:
    cat <<EOF >> /home/ssm-user/client-iam.properties
    ssl.truststore.location=/home/ssm-user/cacerts
    ssl.truststore.password=changeit
    EOF

  7. Verify you can connect to the cluster using IAM authentication using our new custom domain name, replacing bootstrap.example.com with your own custom domain name if you used a different one in CloudFormation:
    bin/kafka-topics.sh --list --command-config client-iam.properties --bootstrap-server bootstrap.example.com:9000

Cleanup

To stop incurring costs navigate to CloudFormation and delete the CloudFormation stack to remove all resources provisioned by CloudFormation.

Frequently Asked Question about Custom Domain Name

Customers have asked a few questions about implementing custom domain names with MSK. You can find answers to some of the most popular questions here.

Are there any limitations for this solution on MSK?

The advertised.listeners setting was removed as a dynamic broker in KRaft-based Kafka clusters. Therefore, this solution is only supported in Zookeeper-based MSK clusters. Additionally, this solution is only applicable to SASL/SCRAM and IAM-authentication based MSK clusters.

How the custom domain name solution scales when we add new brokers?

When using the NLB for broker connectivity (option 2 in the configure a custom domain name for your Amazon MSK cluster blog post), you will need to add an additional listener for each additional broker created.

For TLS, if using Subject Alternative Name (SAN) to list individual broker DNS hostnames, you will need to create a new certificate that includes the names of the additional brokers. One option is to create a certificate with SANs for more brokers than needed to allow for growth.If a wildcard certificate is used, you do not need to modify certificates when adding brokers.

What changes are required when we remove brokers?

Amazon MSK supports scale-in by removing brokers from the cluster. Brokers are removed from each availability zones (AZ). So a 6 broker Amazon MSK cluster deployed in 3 AZ can be reduced to 3 broker cluster deployed in 3 AZ. When brokers are removed, you can remove the NLB listeners for the removed broker along with the Route53 DNS endpoints. However, you can also leave them as is, or just remove the target IP from the broker numbers target group. The NLB will mark the targets as unhealthy and stop directing traffic to them. If you ever plan to scale-out the number of brokers, you can re-use the existing NLB listeners and Route 53 DNS entries and would only need to update the target IPs used in the broker numbers target group.

Is there any change in configuration required if there is any broker failure?

No. When a broker fails, Amazon MSK replaces the failed broker with a new broker instance keeping the configuration of the broker exactly the same. So, there would be no change in the advertised listener of the broker. Once the broker is healthy, the broker can accept new connections and read/write traffic.

Can you use Amazon MSK Replicator between MSK clusters in multiple AWS Regions when using the custom domain name solution?

The Amazon MSK Replicator can be used when using the custom domain name solution, either in an active-passive or active-active setup. The same process can be followed to set the custom domain name.

You then follow build multi-Region resilient Apache Kafka applications with identical topic names using Amazon MSK and Amazon MSK Replicator post to configure MSK Replicator.

The following diagram shows an active-active AWS multi-Region MSK setup using the custom domain name solution:

Can I use a global bootstrap DNS name to connect to Amazon MSK clusters deployed across multiple AWS regions when IAM authentication is enabled?

No, it is not possible to use a global bootstrap reference to represent MSK clusters deployed in multiple AWS Regions, unless the client is aware of the cluster’s region when connecting. To use IAM authentication, the correct AWS Region must be included in the IAM authentication request for a given cluster. This is because the AWS Region is a part of the Sigv4 authentication protocol used by IAM. This scope prevents the IAM authorization being used to talk to a resource in another AWS Region. You can provide the AWS Region in one of two ways– with region-specific bootstrap URLs or by explicitly configuring the region.

For example, if the bootstrap string is bootstrap.us-east-1.example.com, then msk-iam-auth library will to extract the AWS Region from the broker connection string and use us-east-1 in its IAM requests. If the bootstrap string is simply bootstrap.example.com, then the client must explicitly configure AWS_REGION=us-east-1 to connect to the cluster if it is in us-east-1, or us-west-2 if it is in us-west-2.

Note that this is a limitation for IAM authentication, but not for SASL/SCRAM authentication. With SASL/SCRAM authentication, if the client’s credentials are applied to both clusters the global endpoint can point to either cluster and the client will be able to connect. The AWS Region is not used in SASL/SCRAM authentication, so it does not restrict the authentication scope.

How to allow public access to a private MSK cluster using the custom domain name solution?

To provide public access to a MSK cluster using the custom domain solution, you will need to do the following:

  • Create an Internet-facing NLB, and associate public subnets (subnets that have a route to the Internet Gateway attached to the VPC).
  • Create ingress rules in both the NLB and MSK security groups permitting the required public addresses. Note: the port will be 9098 for the MSK security group, and the ports you are using on the NLB listeners.
  • Provide public DNS resolution for the Kafka clients, by using a Route 53 public zone, or an alternative public DNS resolver.
  • The client needs have IAM credentials, with permission, to talk to the MSK brokers, using an IAM roleIAM access keys, IAM Roles Anywhere, or another mechanism that uses the AWS Security Token Service (AWS STS) to create and provide trusted users with temporary security credentials.

In the first part of the blog, two patterns have been highlighted. How to decide which pattern to use and why?

Option 1: Only bootstrap connection through NLB

If the Kafka clients have direct access to the broker, then you can use custom domain name for the bootstrap connection while the clients can still connect to the MSK Brokers with broker DNS. This is the simplest option, as it does not require custom TLS certificates or TLS listeners.Note that this option is not necessary when using MSK Express brokers, as MSK Express brokers already manages bootstrapping via a broker-agnostic connection string. For MSK Express, this option does not add value other than configuring a custom domain name for appearances / simplicity of client configuration. For MSK Standard brokers, this can improve client connectivity by making connection strings broker agnostic.

Option 2: All connections through NLB

When Kafka clients don’t have direct access to Amazon MSK Brokers, routing all connections through the NLB can be preferred. This can occur when a client is deployed in a different VPC than Amazon MSK VPC or the client is external, and when Amazon MSK Multi VPC Connectivity is not an option. In general, Amazon MSK Multi VPC Connectivity is preferred as this is a simpler pattern for most organizations to manage MSK Connectivity across accounts and VPCs.When Multi VPC Connectivity is not an option, NLB can be used to provide connectivity with Transit Gateway or PrivateLink, and the solution mentioned in the blog should be used.

Here is an example architecture how Kafka client and Amazon MSK cluster deployed in two separate VPCs but connected via AWS Private Link.

Is Amazon Route 53 required to use a custom domain name with Amazon MSK?

You can use an alternative DNS resolver service, and do not require Amazon Route 53 to use a custom domain name with Amazon MSK. The only requirement is that your clients can resolve against your DNS resolver service. The only change required, is to use a CNAME for the DNS records, referencing the NLBs DNS record, in place of the Alias records, as this is record type is only available in Amazon Route 53.

We don’t use Amazon Certificate Manager (ACM), can NLB integrate with other 3rd party certificate managers?

NLB only supports ACM to bind a certificate to a TLS listener. You can import a certificate created using your 3rd party certificate manager into ACM, and do not need to create a certificate using ACM.

Getting connection to node terminated during authentication after setting advertised.listeners , what could be the issue?

As the issue started to occur after changing the advertised.listeners configuration, the issue is unlikely to be related to permissions. The following can cause this issue:

  • The NLB and/or client’s Security Group does not permit access to the listener ports on the NLB from the client.
  • A firewall appliance between the NLB and client does not permit the client to talk to the NLB using the listener ports.
  • The advertised.listeners configuration has an error causing the client to receive invalid details, such as a typo in the name. If this is the case, use a client in the same VPC as the MSK broker that has IAM permissions to talk to the MSK broker, and Security Group rules permitting connectivity, you then use the following command to delete the advertised.listeners configuration.
/home/ec2-user/kafka/bin/kafka-configs.sh --alter \
         --bootstrap-server  \
         --entity-type brokers \
         --entity-name  \
         --command-config ~/kafka/config/client_iam.properties \
         --delete-config advertised.listeners

BROKERS_AMAZON_DNS_NAME such as b-1.clustername.xxxxxx.yy.kafka.region.amazonaws.com:9098.

Getting “unexpected broker id, expected 2 or empty string, but received 1”, what is causing this error?

This error is typically presented when the advertised.listeners configuration for one of the brokers has the port used by another broker set. For example broker 2 has port 9001 set for IAM, but this port is used to connect to broker 1, so broker 1 is responding with an error to say you presented broker id 2, but I am broker 1.

To correct this, you will need to update the broker with the incorrect advertised.listeners configuration to use the correct port. To gain access to the broker to make the change, you will need to use the following command to delete the incorrect configuration:

/home/ec2-user/kafka/bin/kafka-configs.sh --alter \
         --bootstrap-server \
         --entity-type brokers \
         --entity-name  \
         --command-config ~/kafka/config/client_iam.properties \
         --delete-config advertised.listeners

BROKERS_AMAZON_DNS_NAME such as b-2.clustername.xxxxxx.yy.kafka.region.amazonaws.com:9098.

You then need to use the following command to set the advertised.listeners configuration for that broker:

Note: The advertised.listeners configuration in the below assumes only IAM is used for authentication. If you are using additional authentication options, you will need to include them.

MSKDOMAIN=
broker_id=
Domain=

/home/ec2-user/kafka/bin/kafka-configs.sh --alter \
         --bootstrap-server  \
         --entity-type brokers \
         --entity-name "$broker_id" \
         --command-config ~/kafka/config/client_iam.properties \
         --add-config "advertised.listeners=[CLIENT_IAM://b-$broker_id.$Domain:900$broker_id,REPLICATION://b-$broker_id-internal.$MSKDOMAIN:9093,REPLICATION_SECURE://b-$broker_id-internal.$MSKDOMAIN:9095]"

Summary

In this post, we explained how you can use an NLB, Route 53, and the advertised listener configuration option in Amazon MSK to support custom domain names with MSK clusters when using IAM authentication. You can use this solution to keep your existing Kafka bootstrap DNS name and reduce or remove the need to change client applications because of a migration, recovery process, or to use a DNS name in line with your organization’s naming convention (for example, msk.prod.example.com).

Try the solution out for yourself, and leave your questions and feedback in the comments section.


About the authors

Subham Rakshit

Subham Rakshit

Subham is a Senior Streaming Solutions Architect for Analytics at AWS based in the UK. He works with customers to design and build streaming architectures so they can get value from analyzing their streaming data. His two little daughters keep him occupied most of the time outside work, and he loves solving jigsaw puzzles with them.

Mark Taylor

Mark Taylor

Mark is a Senior Technical Account Manager at AWS, working with enterprise customers to implement best practices, optimize AWS usage, and address business challenges. Mark lives in Folkestone, England, with his wife and two dogs. Outside of work, he enjoys watching and playing football, watching movies, playing board games, and traveling.

Mazrim Mehrtens

Mazrim is a Sr. Specialist Solutions Architect for messaging and streaming workloads. Mazrim works with customers to build and support systems that process and analyze terabytes of streaming data in real time, run enterprise Machine Learning pipelines, and create systems to share data across teams seamlessly with varying data toolsets and software stacks.

Migrate third-party and self-managed Apache Kafka clusters to Amazon MSK Express brokers with Amazon MSK Replicator

Post Syndicated from Ankita Mishra original https://aws.amazon.com/blogs/big-data/migrate-third-party-and-self-managed-apache-kafka-clusters-to-amazon-msk-express-brokers-with-amazon-msk-replicator/

Migrating Apache Kafka workloads to the cloud often involves managing complex replication infrastructure, coordinating application cutovers with extended downtime windows, and maintaining deep expertise in open-source tools like Apache Kafka’s MirrorMaker 2 (MM2). These challenges slow down migrations and increase operational risk. Amazon MSK Replicator addresses these challenges, enabling you to migrate your Kafka deployments (referred to as “external” Kafka clusters) to Amazon MSK Express brokers with minimal operational overhead and reduced downtime. MSK Replicator supports data migration from Kafka deployments (version 2.8.1 or later) that have SASL/SCRAM authentication enabled – including Kafka clusters running on-premises, on AWS, or other cloud providers, as well as Kafka-protocol-compatible services like Confluent Platform, Avien, RedPanda, WarpStream, or AutoMQ when configured with SASL/SCRAM authentication.

In this post, we walk you through how to replicate Apache Kafka data from your external Apache Kafka deployments to Amazon MSK Express brokers using MSK Replicator. You will learn how to configure authentication on your external cluster, establish network connectivity, set up bidirectional replication, and monitor replication health to achieve a low-downtime migration.

How it works

MSK Replicator is a fully managed serverless service that replicates topics, configurations, and offsets from cluster to cluster. It alleviates the need to manage complex infrastructure or configure open-source tools.

Before MSK Replicator, customers used tools like MM2 for migrations. These tools lack bi-directional topic replication when using the same topic names, creating complex application architectures to consume different topics on different clusters. Custom replication policies in MM2 can allow identical topic names, but MM2 still lacks bidirectional offset replication because the MM2 architecture requires producers and consumers to run on the same cluster to replicate offsets. This created complex migrations that required either migrating consumers before producers or big-bang migrations migrating all applications at once. When customers run into issues during the migration, the rollback process is error-prone and introduces large amounts of duplicate message processing due to the lack of consumer group offset synchronization. These approaches create risk and complexity for customers that make migrations difficult to manage.

MSK Replicator addresses these problems by supporting bidirectional replication of data and enhanced consumer group offset synchronization. MSK Replicator copies topics and offsets from an external Kafka cluster to MSK, allowing you to preserve the same topic and consumer group names on both clusters. MSK Replicator also supports creating a second Replicator instance for bidirectional replication of both data and enhanced offset synchronization, allowing producers and consumers to run independently on different Kafka clusters. Data published or consumed on the Amazon MSK cluster will be replicated back to the external cluster by the second Replicator. This feature works when producers and consumers are migrated regardless of order without worrying about dependencies between applications.

Because MSK Replicator provides bidirectional data replication and enhanced consumer group offset synchronization, you can move producers and consumers at your own pace without data loss. This reduces migration complexity, allowing you to migrate applications between your external Kafka cluster and Amazon MSK regardless of order. If you run into problems during the migration, enhanced offset synchronization allows you to roll back changes by moving applications back to the external Kafka cluster, where they restart from the latest checkpoint from the Amazon MSK cluster.

For example, consider three applications:

  1. The “Orders” application, which accepts incoming orders and writes them to the orders Kafka topic
  2. The “Order status” application, which reads from the “orders” Kafka topic and writes status updates to the order_status topic
  3. The “Customer notification” application, which reads from the order_status topic and notifies customers when status changes

MSK Replicator enables these applications to be migrated between an on-premises Apache Kafka cluster and an Amazon MSK Express cluster with low downtime and no data loss, regardless of order. The “Order status” application can migrate first, receive orders from the on-premises “Orders” application, and send status updates to the on-premises “Customer notification” application. If issues arise during the migration, the “Order status” application can roll back to the on-premises cluster and its consumer group offsets for the orders topic will be ready for it to pick up from where it left off on the Amazon MSK cluster.

MSK Replicator supports data distribution across hybrid and multi-cloud environments for analytics, compliance, and business continuity. It is also configured for disaster recovery scenarios where Amazon MSK Express serves as a resilient target for your external Kafka clusters.

If you are currently using MM2 for replication, see Amazon MSK Replicator and MirrorMaker2: Choosing the right replication strategy for Apache Kafka disaster recovery and migrations to understand which solution best fits your use case.

Solution overview

MSK Replicator supports Kafka deployments running version 2.8.1 or later as a source, including 3rd party managed Kafka services, self-managed Kafka, and on-premises or third-party cloud-hosted Kafka. MSK Replicator automatically handles data transfer, uses SASL/SCRAM authentication with SSL encryption, and maintains consumer group positions across both clusters. If you do not use SASL/SCRAM today, this can be configured as a new listener used for MSK Replicator allowing current clients to use their existing authentication mechanisms alongside MSK Replicator.

Prerequisites

To follow along with this walkthrough, you need the following resources in place:

Setting up replication

Step 1: Configure network connectivity

You can set up network connectivity between your external Kafka cluster and your AWS VPC using methods such as AWS Direct Connect for dedicated network connections, AWS Site-to-Site VPN for encrypted connections over the internet, and AWS VPC peering or AWS Transit Gateway for connections between AWS VPCs. Verify that IP routing and DNS resolution are properly configured between your external cluster and AWS.

To verify IP routing and DNS resolution, connect to your external Kafka cluster from inside of your VPC by using the Kafka CLI to list topics on the external cluster. If you can list topics from your VPC using the Kafka CLI, this means DNS resolution and IP routing are working successfully. If it fails, work with your network admins to troubleshoot network connectivity issues.

Step 2: Configure external cluster

In this step, you will set up authentication on your external Kafka cluster and store the credentials in AWS Secrets Manager so that MSK Replicator can connect securely.

Configure authentication

Using the external cluster admin user, configure SASL/SCRAM authentication for MSK Replicator using SHA-256 or 512 on your external Kafka cluster. Create a SASL/SCRAM user for MSK Replicator and give the user the following ACL permissions:

  • Topic operations – Alter, AlterConfigs, Create, Describe, DescribeConfigs, Read, Write
  • Group operations – Read, Describe
  • Cluster operations – Create, ClusterAction, Describe, DescribeConfigs

Configure SecretsManager

AWS Secrets Manager stores your SASL/SCRAM credentials securely so that MSK Replicator can retrieve them at runtime. The secret must use JSON format and have the following keys:

  • username – The SCRAM username that you configured in the authentication step above
  • password – The SCRAM password that you configured in the authentication step above
  • certificate – The public root CA certificate (the top-level certificate authority that issued your cluster’s TLS certificate) and the intermediate CA chain (intermediate certificates between the root and your cluster’s certificate), used for SSL handshakes with the external cluster

Optionally, you may create separate secrets for SCRAM credentials and the SSL certificate. This approach is useful when secrets for SCRAM credentials and certificates are provisioned in different stages, such as in Infrastructure as Code (IaC) pipelines.

Retrieve the cluster ID

As the admin user, use the Kafka CLI tools to retrieve the cluster ID of your external cluster. Run the following command, replacing your-broker-host:9096 with the address of one of your external cluster’s bootstrap servers:

bin/kafka-cluster.sh cluster-id --bootstrap-server your-broker-host:9096 --config admin.properties

The command returns a cluster ID string such as lkc-abc123. Take note of this value because you will need it when creating the replicator in Step 4.

Step 3: Create your MSK Express target cluster

With your external cluster configured, you can now set up the target. Create an Amazon MSK Express cluster with IAM authentication enabled. Make sure that the cluster is in subnets that have access to AWS Secrets Manager endpoints. See Get started using Amazon MSK for more information on creating an MSK cluster.

Step 4: Create the replicator

Now that both clusters are ready, you can connect them by setting up the MSK Replicator with the appropriate IAM role and replication configuration.

Set up an IAM role for MSK Replicator

MSK Replicator needs an IAM role to interact with your MSK Express cluster and retrieve secrets. Set up a service execution IAM role with a trust policy allowing kafka.amazonaws.com and attach the AWSMSKReplicatorExecutionRole permissions policy. Take note of the role ARN for creating the replicator.

Create and attach a policy for accessing your Secrets Manager secrets and reading/writing data in your MSK cluster. See Creating roles and attaching policies (console) for more information on creating IAM roles and policies.

The following is an example policy for reading and writing data to your MSK cluster and reading KMS-encrypted Secrets Manager secrets:

{ 
    "Version": "2012-10-17", 
    "Statement": [ 
        { 
            "Sid": "SecretsManagerAccess", 
            "Effect": "Allow", 
            "Action": [ 
                "secretsmanager:GetSecretValue", 
                "secretsmanager:DescribeSecret" 
            ], 
            "Resource": [ 
                "<SCRAM_SECRET_ARN>", 
                "<CERT_SECRET_ARN>" 
            ] 
        }, 
        { 
            "Sid": "KMSDecrypt", 
            "Effect": "Allow", 
            "Action": "kms:Decrypt", 
            "Resource": "<SECRETSMANAGER_KMS_KEY_ARN>" 
        }, 
        { 
            "Sid": "TargetClusterAccess", 
            "Effect": "Allow", 
            "Action": [ 
                "kafka-cluster:Connect", 
                "kafka-cluster:DescribeCluster", 
                "kafka-cluster:AlterCluster", 
                "kafka-cluster:DescribeClusterDynamicConfiguration", 
                "kafka-cluster:AlterClusterDynamicConfiguration", 
                "kafka-cluster:DescribeTopic", 
                "kafka-cluster:CreateTopic", 
                "kafka-cluster:AlterTopic", 
                "kafka-cluster:DescribeTopicDynamicConfiguration", 
                "kafka-cluster:AlterTopicDynamicConfiguration", 
                "kafka-cluster:WriteData", 
                "kafka-cluster:WriteDataIdempotently", 
                "kafka-cluster:ReadData", 
                "kafka-cluster:DescribeGroup", 
                "kafka-cluster:AlterGroup" 
            ], 
            "Resource": [ 
                "arn:aws:kafka:<REGION>:<ACCOUNT_ID>:cluster/<MSK_CLUSTER_NAME>*/*", 
                "arn:aws:kafka:<REGION>:<ACCOUNT_ID>:topic/<MSK_CLUSTER_NAME>/*", 
                "arn:aws:kafka:<REGION>:<ACCOUNT_ID>:group/<MSK_CLUSTER_NAME>*/*" 
            ] 
        }, 
        { 
            "Sid": "CloudWatchLogsAccess", 
            "Effect": "Allow", 
            "Action": [ 
                "logs:CreateLogStream", 
                "logs:PutLogEvents", 
                "logs:DescribeLogStreams" 
            ], 
            "Resource": "<MSK_REPLICATOR_LOG_GROUP_ARN>" 
        } 
    ] 
}

Create the replicator for external to MSK replication

Use the AWS CLI, API, or Console to create your replicator. Here’s an example using the AWS CLI:

aws kafka create-replicator \
  --replicator-name external-to-msk \
  --service-execution-role-arn "arn:aws:iam::123456789012:role/MSKReplicatorRole" \
  --kafka-clusters file://./kafka-clusters.json \
  --replication-info-list file://./replication-info.json \
  --log-delivery file://./log-delivery.json \
  --region us-east-1

The kafka-clusters.json file defines the source and target Kafka cluster connection information, replication-info.json specifies which topics to replicate and how to handle consumer group offset synchronization, and log-delivery.json specifies the CloudWatch logging configuration. The following tables describe the required parameters:

CLI inputs:

CLI Parameter Description Example
replicator-name The name of the replicator external-to-msk
service-execution-role-arn The ARN for the service execution IAM role you created arn:aws:iam::123456789012:role/MSKReplicatorRole
kafka-clusters The Kafka cluster connection info See below
replication-info-list The replication configuration See below
log-delivery The logging configuration See below

Key kafka-clusters.json inputs:

CLI Parameter Description Example
ApacheKafkaClusterId The cluster ID retrieved in Step 2 lkc-abc123
RootCaCertificate The Secrets Manager ARN containing the public CA certificate and intermediate CA chain arn:aws:secretsmanager:<REGION>:<ACCOUNT_ID>:secret:my-cert
MskClusterArn The ARN for the MSK Express cluster arn:aws:kafka:<REGION>:<ACCOUNT_ID>:cluster/my-cluster/abc-123
SecretArn The Secrets Manager ARN containing the SASL/SCRAM username and password arn:aws:secretsmanager:<REGION>:<ACCOUNT_ID>:secret:my-creds
SecurityGroupIds The security group IDs for MSK Replicator sg-0123456789abcdef0

Key replication-info.json inputs:

CLI Parameter Description Example
TargetCompressionType The compression type to use for replicating data LZ4
TopicsToReplicate The list of topics to replicate (use [“.*”] for all topics) [“my-topic”]
ConsumerGroupsToReplicate The list of consumer groups to replicate [“my-group”]
StartingPosition The point in the Kafka topics to begin replication from (either EARLIEST or LATEST) EARLIEST
ConsumerGroupOffsetSyncMode Whether or not to use enhanced bidirectional consumer group offset synchronization ENHANCED

Note that startingPosition is set to EARLIEST in the configuration below, which means the replicator begins reading from the oldest available offset on each topic. This is the recommended setting for migrations to avoid data loss.

Key log-delivery.json inputs:

CLI Parameter Description Example
Enabled Allows you to enable CloudWatch logging true
LogGroup The CloudWatch logs log group name to log to /msk/replicator/my-replicator

Additional log delivery methods for Amazon S3 and Amazon Data Firehose are supported. In this post, we use CloudWatch logging.

The configs should look like the following for external to MSK replication.

kafka-clusters.json:

[ 
  { 
    "ApacheKafkaCluster": { 
      "ApacheKafkaClusterId": "lkc-abc123", 
      "BootstrapBrokerString": "broker1.example.com:9096" 
    }, 
    "ClientAuthentication": { 
      "SaslScram": { 
        "Mechanism": "SHA512", 
        "SecretArn": "arn:aws:secretsmanager:<REGION>:<ACCOUNT_ID>:secret:my-creds" 
      } 
    }, 
    "EncryptionInTransit": { 
      "EncryptionType": "TLS", 
      "RootCaCertificate": "arn:aws:secretsmanager:<REGION>:<ACCOUNT_ID>:secret:my-cert" 
    } 
  }, 
  { 
    "AmazonMskCluster": { 
      "MskClusterArn": "arn:aws:kafka:<REGION>:<ACCOUNT_ID>:cluster/my-cluster/abc-123" 
    }, 
    "VpcConfig": { 
      "SecurityGroupIds": ["sg-0123456789abcdef0"], 
      "SubnetIds": ["subnet-abc123", "subnet-abc124", "subnet-abc125"] 
    } 
  } 
] 

replication-info.json: 

[ 
  { 
    "SourceKafkaClusterId": "lkc-abc123", 
    "TargetKafkaClusterArn": "arn:aws:kafka:<REGION>:<ACCOUNT_ID>:cluster/my-cluster/abc-123", 
    "TargetCompressionType": "LZ4", 
    "TopicReplication": { 
      "TopicsToReplicate": ["my-topic"], 
      "CopyTopicConfigurations": true, 
      "CopyAccessControlListsForTopics": true, 
      "DetectAndCopyNewTopics": true, 
      "StartingPosition": {"Type": "EARLIEST"}, 
      "TopicNameConfiguration": {"Type": "IDENTICAL"} 
    }, 
    "ConsumerGroupReplication": { 
      "ConsumerGroupsToReplicate": ["my-group"], 
      "SynchroniseConsumerGroupOffsets": true, 
      "DetectAndCopyNewConsumerGroups": true, 
      "ConsumerGroupOffsetSyncMode": "ENHANCED" 
    } 
  } 
] 

log-delivery.json: 

{ 
  "ReplicatorLogDelivery": {
     "CloudWatchLogs": {
       "Enabled": true, 
       "LogGroup": "<LOG_GROUP_NAME>"
     }
  } 
}

Configure bidirectional replication from MSK to the external cluster

To enable bidirectional replication, create a second replicator that replicates in the opposite direction. Use the same IAM role and network configuration from Step 4, but swap the source and target. Replace SourceKafkaClusterId with TargetKafkaClusterId and TargetKafkaClusterArn with SourceKafkaClusterArn in a new msk-to-external-replication-info.json file:

aws kafka create-replicator \
  --replicator-name msk-to-external \
  --service-execution-role-arn "arn:aws:iam::123456789012:role/MSKReplicatorRole" \
  --kafka-clusters file:///./kafka-clusters.json \
  --replication-info-list file:///./msk-to-external-replication-info.json \
  --log-delivery file:///./log-delivery.json \
  --region us-east-1

Monitoring replication health

Monitor your replication using Amazon CloudWatch metrics. Three key metrics to understand are MessageLag, SumOffsetLag, and ReplicationLatency. MessageLag measures how far behind the replicator is from the external cluster in terms of messages not yet replicated, while SumOffsetLag measures how far behind a consumer group is from the latest message in a topic. ReplicationLatency is the amount of latency between the source and target clusters in data replication. When the three reach a sustained low level, your clusters are fully synchronized for both data and consumer group offsets.

To troubleshoot MSK Replicator replication or errors, use the CloudWatch logs to get more details about the health of the replicator. MSK Replicator logs status and troubleshooting information which can be helpful in diagnosing issues like connectivity, authentication, and SSL errors.

Note that the replication is asynchronous, so there will be some lag during replication. The lag will reach zero once a client is shut down during migration to the target cluster. This takes about 30 seconds under normal operations, allowing a low downtime migration without data loss. If your lag is continually increasing or does not reach a sustained low level, this indicates that you have insufficient partitions for high-throughput replication. Refer to Troubleshoot MSK Replicator for more information on troubleshooting replication throughput and lag.

Key metrics include:

  • MessageLag – Monitors the sync between the MSK Replicator and the source cluster. MessageLag indicates the lag between the messages produced to the source cluster and messages consumed by the replicator. It is not the lag between the source and target cluster.
  • ReplicationLatency – Time taken for records to replicate from source to target cluster (ms)
  • ReplicatorThroughput – Average number of bytes replicated per second
  • ReplicatorFailure – Number of failures the replicator is experiencing
  • KafkaClusterPingSuccessCount – Connection health indicator (1 = healthy, 0 = unhealthy)
  • ConsumerGroupCount – Total consumer groups being synchronized
  • ConsumerGroupOffsetSyncFailure – Failures during offset synchronization
  • AuthError – Number of connections with failed authentication per second, by cluster
  • ThrottleTime – Average time in ms a request was throttled by brokers, by cluster
  • SumOffsetLag – Aggregated offset lag across partitions for a consumer group on a topic (MSK cluster-level metric)

For more details on these metrics, see the MSK Replicator metrics documentation.

Your applications are ready to migrate when the following conditions are met. For most workloads, you should expect these metrics to stabilize within a few hours of starting replication. High-throughput clusters may take longer depending on topic volume and partition count.

  • ReplicatorFailure = 0
  • ConsumerGroupOffsetSyncFailure = 0
  • KafkaClusterPingSuccessCount = 1 for both source and target clusters
  • MessageLag < 1,000
    • Your sustained lag may be lower or higher depending on your throughput per partition, message size, and other factors
    • Sustained high message lag usually indicates insufficient partitions for high-throughput replication
  • ReplicationLatency < 90 seconds
    • Your sustained latency may be lower or higher depending on your throughput per partition, message size, and other factors
    • Sustained high latency usually indicates insufficient partitions for high-throughput replication
  • SumOffsetLag is at a sustained low level on both clusters
    • Offset values on the two clusters may not be numerically identical.
    • MSK Replicator translates offsets between clusters so that consumers resume from the correct position, but the raw offset numbers can differ due to how offset translation works. What matters is that SumOffsetLag is at a sustained low level.
  • ConsumerGroupCount (MSK) = Expected count (external cluster)
    • If ConsumerGroupCount is zero or does not match the expected count, then there is an issue in the Replicator configuration or a permissions issue preventing consumer group synchronization

Migrating your applications

With bidirectional consumer offset synchronization, you can migrate your producers and consumers regardless of order. Start by monitoring replication metrics until they reach the target values described in the previous section. Then migrate your applications (producers or consumers) to use the MSK Express cluster endpoints and verify that they are producing and consuming as expected. If you encounter issues, you can roll back by switching applications back to the external cluster. The consumer offset synchronization makes sure that your applications resume from their last committed position regardless of which cluster they connect to.

For a comprehensive, hands-on walkthrough of the end-to-end migration process, explore the MSK Migration Workshop, which provides step-by-step guidance for migrating your Kafka workloads to Amazon MSK.

Security considerations

MSK Replicator uses SASL/SCRAM authentication with SSL encryption for secure data transfer between your external cluster and AWS. The solution supports both publicly trusted certificates and private or self-signed certificates. Credentials are stored securely in AWS Secrets Manager, and the target MSK Express cluster uses IAM authentication for access control.

When configuring security, keep the following in mind:

  • Make sure that the IAM role you create in Step 4 follows the principle of least privileges. Only attach AWSMSKReplicatorExecutionRole and an IAM policy for Secrets Manager with least-privileges access to read secret values and avoid adding broader permissions.
  • Verify that your Secrets Manager secret is encrypted with an AWS KMS key that the MSK Replicator service execution role has permission to decrypt.
  • Confirm that the security groups assigned to MSK Replicator allow outbound traffic to your external cluster’s broker ports (typically 9096 for SASL/SCRAM with TLS) and to the MSK Express cluster.
  • Rotate your SASL/SCRAM credentials periodically and update the corresponding Secrets Manager secret. MSK Replicator picks up the new credentials automatically on the next connection attempt.

Under the AWS shared responsibility model, AWS is responsible for securing the underlying infrastructure that runs MSK Replicator, including the compute, storage, and networking resources. You are responsible for configuring authentication mechanisms (SASL/SCRAM), managing credentials in AWS Secrets Manager, configuring network security (security groups and VPC settings), implementing IAM policies following least privilege, and rotating credentials. For more information, see Security in Amazon MSK in the Amazon MSK Developer Guide.

Cleanup

To avoid ongoing charges, delete the resources you created during this walkthrough. Start by deleting the replicators first, because they depend on the other resources:

aws kafka delete-replicator --replicator-arn <replicator-arn>

After both replicators are deleted, you can remove the following resources if they were created solely for this walkthrough:

  1. The MSK Express cluster (deleting a cluster also removes its stored data, so verify that your applications have fully migrated before proceeding)
  2. The Secrets Manager secrets containing your SASL/SCRAM credentials and certificates
  3. The IAM role and policies created for MSK Replicator

You can verify that a replicator has been fully deleted by running aws kafka list-replicators and confirming it no longer appears in the output.

Conclusion

Amazon MSK Replicator simplifies the process of migrating to Amazon MSK Express brokers and establishes hybrid Kafka architectures. The fully managed service alleviates the operational complexity of managing replication while bidirectional consumer offset synchronization enables flexible, low-risk application migration.

Next Steps

To get started using MSK Replicator to migrate applications to MSK Express brokers, use the MSK Migration Workshop for a hands-on, end-to-end migration walkthrough. The Amazon MSK Replicator documentation includes detailed configuration details to help configure MSK Replicator for your use case. From there, use MSK Replicator to migrate your Apache Kafka workloads to MSK Express broker.

Once your migration is complete, consider exploring multi-region replication patterns for disaster recovery, or integrating your MSK Express cluster with AWS analytics services such as Amazon Data Firehose and Amazon Athena. If you need help planning your migration, reach out to your AWS account team, AWS Support or AWS Professional Services.


About the authors

Ankita Mishra

Ankita is a Product Manager for Amazon Managed Streaming for Apache Kafka. She works closely with AWS customers to understand their needs for real-time analytics and high throughput, low latency streaming workloads. Working backwards from their needs, she helps drive the MSK roadmap and deliver new innovations that help AWS customers focus on building novel streaming applications.

Mazrim Mehrtens

Mazrim is a Sr. Specialist Solutions Architect for messaging and streaming workloads. Mazrim works with customers to build and support systems that process and analyze terabytes of streaming data in real time, run enterprise Machine Learning pipelines, and create systems to share data across teams seamlessly with varying data toolsets and software stacks.

Introducing Amazon MSK Express Broker power for Kiro

Post Syndicated from Stephan Schiller original https://aws.amazon.com/blogs/big-data/introducing-amazon-msk-express-broker-power-for-kiro/

Developers working with Amazon Managed Streaming for Apache Kafka (Amazon MSK) regularly need to make decisions that require deep operational context—choosing the right instance type, diagnosing consumer lag, or planning for a traffic spike. Answering these questions means piecing together documentation, metrics, and operational know-how.

What if your IDE could guide you through that workflow with built-in domain expertise and tooling? Kiro is an AI-powered agentic IDE that lets you describe what you need in natural language. Whether it’s infrastructure configuration or operational troubleshooting, Kiro guides you through the solution.

In this post, we’ll show you how to use Kiro powers, a new capability that equips Kiro with contextual knowledge and tooling. You can simplify your MSK cluster management, from initial setup to diagnosing common issues, all through natural language conversations.

Challenges operating your MSK Express broker cluster

Amazon MSK Express Brokers are a fully managed offering where AWS handles much of the underlying infrastructure. However, platform teams still need to correctly size clusters based on throughput requirements. They also need to understand the right Amazon CloudWatch metrics during performance issues and investigate when CPU usage or replication lag is higher than expected. MSK best practices documentation spans multiple AWS guides. This makes it time-consuming to find relevant information during production incidents. New team members face a learning curve with MSK operations and can repeat common sizing and configuration mistakes.

Although Express Brokers simplify infrastructure management, you still face operational challenges that require deep Kafka expertise across three areas:

  • Cluster creation and sizing: You must still select the right instance type, configure networking, and choose authentication methods. These decisions impact cost and performance from day one.
  • Observability and troubleshooting: Effective operations require correlating broker, partition, and client metrics. Troubleshooting lag or replication issues still requires a solid understanding of Express Brokers’ architecture.
  • Capacity management: You must monitor CPU usage, understand per-broker throughput limits, and scale before hitting throttling thresholds.

These challenges mean that setting up an MSK cluster, analyzing slow-running clients, or investigating high-CPU load requires pulling together documentation, configuration details, CLI tooling, and operational know-how, which is often spread across multiple sources. Kiro powers address these challenges by bringing best practices, guided workflows, and tooling directly into your IDE, reducing the expertise barrier and the time spent context-switching between documentation, consoles, and the CLI.

Kiro powers

Kiro powers is a feature that combines best practices, specialized context, and tool integrations into a single capability. You can install powers with one click in the Kiro IDE or add them from a public GitHub URL. Each Power combines the following components:

  • Model Context Protocol (MCP) servers give your Kiro agent direct access to your infrastructure. The AWS MSK MCP server, for example, exposes tools to create clusters, monitor health, and optimize configurations.
  • Steering files provide persistent knowledge and workflow guides that Kiro loads based on the user’s task, such as monitoring best practices or troubleshooting workflows.
  • Optional hooks run automated actions when IDE events occur, such as validating configurations before deployment.

The key advantage of Kiro powers is that they load context dynamically based on the user’s task. Instead of configuring every MCP server upfront and re-providing context in each conversation, powers activate the right tools and knowledge on demand. This keeps your agent’s context focused and relevant. In the next section, we look at how these components work together specifically for MSK Express Broker operations.

The MSK Express broker power

The MSK Express broker power packages the AWS MSK MCP server with targeted streaming operations guidance, giving your Kiro agent expertise for MSK Express Broker operations and cluster management. You can use it to build Kafka-based streaming applications through Kiro while maintaining Express broker best practices throughout the development lifecycle.

For cluster operations, you can create Express broker clusters, monitor health metrics, and manage configurations through natural language. You can retrieve cluster metadata, check broker endpoints, and verify replication status. The Power also supports operational monitoring. You can track CPU utilization, throughput limits, partition distribution, and AWS Identity and Access Management (IAM) connection metrics.

To see how this works in practice, here’s what happens when you interact with the Power: When you ask Kiro to create an MSK cluster, the Power recommends appropriate instance sizes based on your throughput requirements. When you’re troubleshooting, it knows to check LeaderCount before diving into network metrics. When you’re troubleshooting authentication failures, it recommends client settings like reconnect.backoff.ms and group.instance.id to resolve connection churn and rebalancing issues against Express broker limits. Use cases include:

  • Cluster sizing and creation: Describe your throughput requirements (for example, “50 MBps ingress with 3x fan-out”) and the Power calculates the right instance type and broker count, then walks through cluster creation.
  • Proactive health monitoring: Ask Kiro to review your cluster. It checks CPU against the 60% threshold, compares throughput to instance limits, and flags partition imbalances and throughput bottlenecks before they become incidents.
  • Incident troubleshooting: Consumer lag spiking? The Power checks the relevant metrics, identifies the root cause (like skewed partition leadership), and guides you through resolution.
  • Capacity planning: Preparing for a traffic spike? The Power analyzes current utilization against instance limits and recommends whether to scale up or add brokers.

The MSK Express broker power brings together documentation, metrics, and operational context so your Kiro agent can correlate findings and help identify root causes specific to your infrastructure.

Getting started with the MSK Express broker power

Starting with Kiro powers takes only a few clicks in the Kiro IDE. You can install from the built-in marketplace or import from a public GitHub URL. Kiro packages all components and makes them available to the Kiro agent.

To set up the MSK Express broker power, follow these steps:

  1. Choose the Powers icon in the Kiro sidebar
  2. In the AVAILABLE panel, scroll down to Build and Operate MSK Express Broker
  3. Choose Install
  4. The power now appears in the INSTALLED panel.

Screenshot of Kiro IDE Powers panel showing installed and available extensions including the MSK Express Broker power.

You can also visit the Kiro powers marketplace to explore other powers.

Conclusion

The MSK Express broker power streamlines Kafka operations by combining Model Context Protocol (MCP) servers with operational guidance. With natural language interactions, you can create clusters, monitor health, optimize configurations, and troubleshoot issues without reviewing extensive documentation.

Install the MSK Express broker power in your Kiro IDE and learn more about Kiro and available Kiro powers.


About the authors

Stephan Schiller

Stephan is a Solutions Architect at AWS, where he has worked since 2023. He brings deep experience from technical roles across multiple hyperscalers and specializes in data analytics and agentic AI systems. He designs and operates scalable data platforms and builds agentic workloads for enterprise environments—helping organizations move from prototypes to production-ready AI systems that are reliable, secure, and deeply integrated with enterprise data landscapes.

Introducing workload simulation workbench for Amazon MSK Express broker

Post Syndicated from Manu Mishra original https://aws.amazon.com/blogs/big-data/introducing-workload-simulation-workbench-for-amazon-msk-express-broker/

Validating Kafka configurations before production deployment can be challenging. In this post, we introduce the workload simulation workbench for Amazon Managed Streaming for Apache Kafka (Amazon MSK) Express Broker. The simulation workbench is a tool that you can use to safely validate your streaming configurations through realistic testing scenarios.

Solution overview

Varying message sizes, partition strategies, throughput requirements, and scaling patterns make it challenging for you to predict how your Apache Kafka configurations will perform in production. The traditional approaches to test these variables create significant barriers: ad-hoc testing lacks consistency, manual set up of temporary clusters is time-consuming and error-prone, production-like environments require dedicated infrastructure teams, and team training often happens in isolation without realistic scenarios. You need a structured way to test and validate these configurations safely before deployment. The workload simulation workbench for MSK Express Broker addresses these challenges by providing a configurable, infrastructure as code (IaC) solution using AWS Cloud Development Kit (AWS CDK) deployments for realistic Apache Kafka testing. The workbench supports configurable workload scenarios, and real-time performance insights.

Express brokers for MSK Provisioned make managing Apache Kafka more streamlined, more cost-effective to run at scale, and more elastic with the low latency that you expect. Each broker node can provide up to 3x more throughput per broker, scale up to 20x faster, and recover 90% quicker compared to standard Apache Kafka brokers. The workload simulation workbench for Amazon MSK Express broker facilitates systematic experimentation with consistent, repeatable results. You can use the workbench for multiple use cases like production capacity planning, progressive training to prepare developers for Apache Kafka operations with increasing complexity, and architecture validation to prove streaming designs and compare different approaches before making production commitments.

Architecture overview

The workbench creates an isolated Apache Kafka testing environment in your AWS account. It deploys a private subnet where consumer and producer applications run as containers, connects to a private MSK Express broker and monitors for performance metrics and visibility. This architecture mirrors the production deployment pattern for experimentation. The following image describes this architecture using AWS services.

MSK Workload SImulator WorkBench Architecture Diagram

This architecture is deployed using the following AWS services:

Amazon Elastic Container Service (Amazon ECS) generate configurable workloads with Java-based producers and consumers, simulating various real-world scenarios through different message sizes and throughput patterns.

Amazon MSK Express Cluster runs Apache Kafka 3.9.0 on Graviton-based instances with hands-free storage management and enhanced performance characteristics.

Dynamic Amazon CloudWatch Dashboards automatically adapt to your configuration, displaying real-time throughput, latency, and resource utilization across different test scenarios.

Secure Amazon Virtual Private Cloud (Amazon VPC) Infrastructure provides private subnets across three Availability Zones with VPC endpoints for secure service communication.

Configuration-driven testing

The workbench provides different configuration options for your Apache Kafka testing environment, so you can customize instance types, broker count, topic distribution, message characteristics, and ingress rate. You can adjust the number of topics, partitions per topic, sender and receiver service instances, and message sizes to match your testing needs. These flexible configurations support two distinct testing approaches to validate different aspects of your Kafka deployment:

Approach 1: Workload validation (single deployment)

Test different workload patterns against the same MSK Express cluster configuration. This is useful for comparing partition strategies, message sizes, and load patterns.

// Fixed MSK Express Cluster Configuration
export const mskBrokerConfig: MskBrokerConfig = {
numberOfBrokers: 1, // 1 broker per AZ = 3 total brokers
instanceType: 'express.m7g.large', // MSK Express instance type
};

// Multiple Concurrent Workload Tests
export const deploymentConfig: DeploymentConfig = { services: [
{ topics: 2, partitionsPerTopic: 6, instances: 3, messageSizeBytes: 1024 }, // High-throughput scenario
{ topics: 1, partitionsPerTopic: 3, instances: 1, messageSizeBytes: 512 }, // Latency-optimized scenario
{ topics: 3, partitionsPerTopic: 4, instances: 2, messageSizeBytes: 4096 }, // Multi-topic scenario
]};

Approach 2: Infrastructure rightsizing (redeploy and compare)

Test different MSK Express cluster configurations by redeploying the workbench with different broker settings while keeping the same workload. This is recommended for rightsizing experiments and understanding the impact of vertical compared to horizontal scaling.

// Baseline: Deploy and test
export const mskBrokerConfig: MskBrokerConfig = { numberOfBrokers: 1, instanceType: 'express.m7g.large',};

// Vertical scaling: Redeploy with larger instances
export const mskBrokerConfig: MskBrokerConfig = { numberOfBrokers: 1,
instanceType: 'express.m7g.xlarge', // Larger instances
};

// Horizontal scaling: Redeploy with more brokers
export const mskBrokerConfig: MskBrokerConfig = {
numberOfBrokers: 2, // More brokers
instanceType: 'express.m7g.large',};

Each redeployment uses the same workload configuration, so you can isolate the impact of infrastructure changes on performance.

Workload testing scenarios (single deployment)

These scenarios test different workload patterns against the same MSK Express cluster:

Partition strategy impact testing

Scenario: You are debating the usage of fewer topics with many partitions compared to many topics with fewer partitions for your microservices architecture. You want to understand how partition count affects throughput and consumer group coordination before making this architectural decision.

const deploymentConfig = { services: [
{ topics: 1, partitionsPerTopic: 1, instances: 2, messageSizeBytes: 1024 }, // Baseline: minimal partitions
{ topics: 1, partitionsPerTopic: 10, instances: 2, messageSizeBytes: 1024 }, // Medium partitions
{ topics: 1, partitionsPerTopic: 20, instances: 2, messageSizeBytes: 1024 }, // High partitions
]};

Message size performance analysis

Scenario: Your application handles different types of events – small IoT sensor readings (256 bytes), medium user activity events (1 KB), and large document processing events (8KB). You must understand how message size impacts your overall system performance and if you should separate these into different topics or handle them together.

const deploymentConfig = { services: [
{ topics: 2, partitionsPerTopic: 6, instances: 3, messageSizeBytes: 256 }, // IoT sensor data
{ topics: 2, partitionsPerTopic: 6, instances: 3, messageSizeBytes: 1024 }, // User events
{ topics: 2, partitionsPerTopic: 6, instances: 3, messageSizeBytes: 8192 }, // Document events
]};

Load testing and scaling validation

Scenario: You expect traffic to vary significantly throughout the day, with peak loads requiring 10× more processing capacity than off-peak hours. You want to validate how your Apache Kafka topics and partitions handle different load levels and understand the performance characteristics before production deployment.

const deploymentConfig = { services: [
{ topics: 2, partitionsPerTopic: 6, instances: 1, messageSizeBytes: 1024 }, // Off-peak load simulation
{ topics: 2, partitionsPerTopic: 6, instances: 5, messageSizeBytes: 1024 }, // Medium load simulation
{ topics: 2, partitionsPerTopic: 6, instances: 10, messageSizeBytes: 1024 }, // Peak load simulation
]};

Infrastructure rightsizing experiments (redeploy and compare)

These scenarios help you understand the impact of different MSK Express cluster configurations by redeploying the workbench with different broker settings:

MSK broker rightsizing analysis

Scenario: You deploy a cluster with basic configuration and put load on it to establish baseline performance. Then you want to experiment with different broker configurations to see the effect of vertical scaling (larger instances) and horizontal scaling (more brokers) to find the right cost-performance balance for your production deployment.

Step 1: Deploy with baseline configuration

// Initial deployment: Basic configuration
export const mskBrokerConfig: MskBrokerConfig = {
numberOfBrokers: 1, // 3 total brokers (1 per AZ)
instanceType: 'express.m7g.large',};export const deploymentConfig: DeploymentConfig = { services: [ { topics: 2, partitionsPerTopic: 6, instances: 3, messageSizeBytes: 1024 }, ]};

Step 2: Redeploy with vertical scaling

// Redeploy: Test vertical scaling impact
export const mskBrokerConfig: MskBrokerConfig = {
numberOfBrokers: 1, // Same broker count
instanceType: 'express.m7g.xlarge', // Larger instances
};

// Keep same workload configuration to compare results

Step 3: Redeploy with horizontal scaling

// Redeploy: Test horizontal scaling impact
export const mskBrokerConfig: MskBrokerConfig = {
numberOfBrokers: 2, // 6 total brokers (2 per AZ)
instanceType: 'express.m7g.large', // Back to original size
};

// Keep same workload configuration to compare results

This rightsizing approach helps you understand how broker configuration changes affect the same workload, so you can improve both performance and cost for your specific requirements.

Performance insights

The workbench provides detailed insights into your Apache Kafka configurations through monitoring and analytics, creating a CloudWatch dashboard that adapts to your configuration. The dashboard starts with a configuration summary showing your MSK Express cluster details and workbench service configurations, helping you to understand what you’re testing. The following image shows the dashboard configuration summary:

The second section of dashboard shows real-time MSK Express cluster metrics including:

  • Broker performance: CPU utilization and memory usage across brokers in your cluster
  • Network activity: Monitor bytes in/out and packet counts per broker to understand network utilization patterns
  • Connection monitoring: Displays active connections and connection patterns to help identify potential bottlenecks
  • Resource utilization: Broker-level resource tracking provides insights into overall cluster health

The following image shows the MSK cluster monitoring dashboard:

The third section of the dashboard shows the Intelligent Rebalancing and Cluster Capacity insights showing:

  • Intelligent rebalancing: in progress: Shows whether a rebalancing operation is currently in progress or has occurred in the past. A value of 1 indicates that rebalancing is actively running, while 0 means that the cluster is in a steady state.
  • Cluster under-provisioned: Indicates whether the cluster has insufficient broker capacity to perform partition rebalancing. A value of 1 means that the cluster is under-provisioned and Intelligent Rebalancing can’t redistribute partitions until more brokers are added or the instance type is upgraded.
  • Global partition count: Displays the total number of unique partitions across all topics in the cluster, excluding replicas. Use this to track partition growth over time and validate your deployment configuration.
  • Leader count per broker: Shows the number of leader partitions assigned to each broker. An uneven distribution indicates partition leadership skew, which can lead to hotspots where certain brokers handle disproportionate read/write traffic.
  • Partition count per broker: Shows the total number of partition replicas hosted on each broker. This metric includes both leader and follower replicas and is key to identifying replica distribution imbalances across the cluster.

The following image shows the Intelligent Rebalancing and Cluster Capacity section of the dashboard:

The fourth section of the dashboard shows the application-level insights showing:

  • System throughput: Displays the total number of messages per second across services, giving you a complete view of system performance
  • Service comparisons: Performs side-by-side performance analysis of different configurations to understand which approaches fit
  • Individual service performance: Each configured service has dedicated throughput tracking widgets for detailed analysis
  • Latency analysis: The end-to-end message delivery times and latency comparisons across different service configurations
  • Message size impact: Performance analysis across different payload sizes helps you understand how message size affects overall system behavior

The following image shows the application performance metrics section of the dashboard:

Getting started

This section walks you through setting up and deploying the workbench in your AWS environment. You will configure the necessary prerequisites, deploy the infrastructure using AWS CDK, and customize your first test.

Prerequisites

You can deploy the solution from the GitHub Repo. You can clone it and run it on your AWS environment. To deploy the artifacts, you will require:

  • AWS account with administrative credentials configured for creating AWS resources.
  • AWS Command Line Interface (AWS CLI) must be configured with appropriate permissions for AWS resource management.
  • AWS Cloud Development Kit (AWS CDK) should be installed globally using npm install -g aws-cdk for infrastructure deployment.
  • Node.js version 20.9 or higher is required, with version 22+ recommended.
  • Docker engine must be installed and running locally as the CDK builds container images during deployment. Docker daemon should be running and accessible to CDK for building the workbench application containers.

Deployment

# Clone the workbench repository
git clone https://github.com/aws-samples/sample-simulation-workbench-for-msk-express-brokers.git

# Install dependencies and build
npm install 
npm run build

# Bootstrap CDK (first time only per account/region)
cd cdk 
npx cdk bootstrap

# Synthesize CloudFormation template (optional verification step)
npx cdk synth

# Deploy to AWS (creates infrastructure and builds containers)
npx cdk deploy

After deployment is completed, you will receive a CloudWatch dashboard URL to monitor the workbench performance in real-time.You can also deploy multiple isolated instances of the workbench in the same AWS account for different teams, environments, or testing scenarios. Each instance operates independently with its own MSK cluster, ECS services, and CloudWatch dashboards.To deploy additional instances, modify the Environment Configuration in cdk/lib/config.ts:

// Instance 1: Development team
export const AppPrefix = 'mske';export const EnvPrefix = 'dev';

// Instance 2: Staging environment (separate deployment)
export const AppPrefix = 'mske';export const EnvPrefix = 'staging';

// Instance 3: Team-specific testing (separate deployment)
export const AppPrefix = 'team-alpha';export const EnvPrefix = 'test';

Each combination of AppPrefix and EnvPrefix creates completely isolated AWS resources so that multiple teams or environments can use the workbench simultaneously without conflicts.

Customizing your first test

You can edit the configuration file located at folder “cdk/lib/config-types.ts” to define your testing scenarios and run the deployment. It is preconfigured with the following configuration:

export const deploymentConfig: DeploymentConfig = { services: [
// Start with a simple baseline test
{ topics: 1, partitionsPerTopic: 3, instances: 1, messageSizeBytes: 1024 },

// Add a comparison scenario
{ topics: 1, partitionsPerTopic: 6, instances: 1, messageSizeBytes: 1024 }, ]};

Best practices

Following a structured approach to benchmarking ensures that your results are reliable and actionable. These best practices will help you isolate performance variables and build a clear understanding of how each configuration change affects your system’s behavior. Begin with single-service configurations to establish baseline performance:

const deploymentConfig = { services: [ { topics: 1, partitionsPerTopic: 3, instances: 1, messageSizeBytes: 1024 } ]};

After you understand the baseline, add comparison scenarios.

Change one variable at a time

For clear insights, modify only one parameter between services:

const deploymentConfig = { services: [
{ topics: 1, partitionsPerTopic: 3, instances: 1, messageSizeBytes: 1024 }, // Baseline
{ topics: 1, partitionsPerTopic: 6, instances: 1, messageSizeBytes: 1024 }, // More partitions
{ topics: 1, partitionsPerTopic: 12, instances: 1, messageSizeBytes: 1024 }, // Even more partitions
]};

This approach helps you understand the impact of specific configuration changes.

Important considerations and limitations

Before relying on workbench results for production decisions, it is important to understand the tool’s intended scope and boundaries. The following considerations will help you set appropriate expectations and make the most effective use of the workbench in your planning process.

Performance testing disclaimer

The workbench is designed as an educational and sizing estimation tool to help teams prepare for MSK Express production deployments. While it provides valuable insights into performance characteristics:

  • Results can vary based on your specific use cases, network conditions, and configurations
  • Use workbench results as guidance for initial sizing and planning
  • Conduct comprehensive performance validation with your actual workloads in production-like environments before final deployment

Recommended usage approach

Production readiness training – Use the workbench to prepare teams for MSK Express capabilities and operations.

Architecture validation – Test streaming architectures and performance expectations using MSK Express enhanced performance characteristics.

Capacity planning – Use MSK Express streamlined sizing approach (throughput-based rather than storage-based) for initial estimates.

Team preparation – Build confidence and expertise with production Apache Kafka implementations using MSK Express.

Conclusion

In this post, we showed how the workload simulation workbench for Amazon MSK Express Broker supports learning and preparation for production deployments through configurable, hands-on testing and experiments. You can use the workbench to validate configurations, build expertise, and improve performance before production deployment. If you’re preparing for your first Apache Kafka deployment, training a team, or improving existing architectures, the workbench provides practical experience and insights needed for success. Refer to Amazon MSK documentation – Complete MSK Express documentation, best practices, and sizing guidance for more information.


About the authors

Manu MishraManu Mishra is a Senior Solutions Architect at AWS with over 18 years of experience in the software industry, specializing in artificial intelligence, data and analytics, and security. His expertise spans strategic oversight and hands-on technical leadership, where he reviews and guides the work of both internal and external customers. Manu collaborates with AWS customers to shape technical strategies that drive impactful business outcomes, providing alignment between technology and organizational goals.

Manu Mishra Ramesh Chidirala is a Senior Solutions Architect at Amazon Web Services with over two decades of technology leadership experience in architecture and digital transformation, helping customers align business strategy and technical execution. He specializes in designing innovative, AI-powered, cost-efficient serverless event-driven architectures and has extensive experience architecting secure, scalable, and resilient cloud solutions for enterprise customers.

Streamline Apache Kafka topic management with Amazon MSK

Post Syndicated from Swapna Bandla original https://aws.amazon.com/blogs/big-data/streamline-apache-kafka-topic-management-with-amazon-msk/

If you manage Apache Kafka today, you know the effort required to manage topics. Whether you use infrastructure as code (IaC) solutions or perform operations with admin clients, setting up topic management takes valuable time that could be spent on building streaming applications.

Amazon Managed Streaming for Apache Kafka (Amazon MSK) now streamlines topic management by supporting new topic APIs and console integration. You can programmatically create, update, and delete Apache Kafka topics using familiar interfaces including AWS Command Line Interface (AWS CLI), AWS SDKs, and AWS CloudFormation. With these APIs, you can define topic properties such as replication factor and partition count and configuration settings like retention and cleanup policies. The Amazon MSK console integrates these APIs, bringing all topic operations to one place. You can now create or update topics with a few selections using guided defaults while gaining comprehensive visibility into topic configurations, partition-level information, and metrics. You can browse for topics within a cluster, review replication settings and partition counts, and go into individual topics to examine detailed configuration, partition-level information, and metrics. A unified dashboard consolidates partition topics and metrics in one view.

In this post, we show you how to use the new topic management capabilities of Amazon MSK to streamline your Apache Kafka operations. We demonstrate how to manage topics through the console, control access with AWS Identity and Access Management (IAM), and bring topic provisioning into your continuous integration and continuous delivery (CI/CD) pipelines.

Prerequisites

To get started with topic management, you need:

  • An active AWS account with appropriate IAM permissions for Amazon MSK.
  • An existing Amazon MSK Express or Standard cluster using Apache Kafka version 3.6 and above.
  • Basic familiarity with Apache Kafka concepts like topics, partitions, and replication.
  • AWS CLI installed and configured (for command line examples).

Creating topics

The MSK console provides a guided experience with sensible defaults while still offering advanced configuration options when you need them.

  1. Navigate to the Amazon MSK console and select your cluster.
  2. Choose the Topics tab, then choose Create topic.
  3. Enter a topic name (for example, customer-orders).
  4. Specify the number of partitions (use the guided defaults or customize based on your needs).
  5. Set the replication factor. Note that Express brokers improve the availability and durability of your Amazon MSK clusters by setting values for critical configurations and protecting them from common misconfiguration. If you try to create a topic with a replication factor value other than 3, Amazon MSK Express will create the topic with a replication factor of 3 by default.
  6. (Optional) Configure advanced settings like retention period or message size limits.
  7. Choose Create topic.

The console validates your configuration and creates the topic. You can create multiple topics simultaneously with the same configuration settings. These topic API responses reflect data that updates approximately every minute. For the most current topic state after making changes, wait approximately one minute before querying.

Configuration considerations

When choosing configuration options, consider your workload requirements:

Viewing and monitoring topics

After you create topics, the MSK console provides comprehensive visibility into their configuration. When you select a specific topic, you will see detailed information:

  • Partitions tab: Shows the distribution of partitions across brokers, including leader assignments and in-sync replica status showcasing Broker IDs for leader and replicas.
  • Configuration tab: Displays all topic-level configuration settings.
  • Monitoring tab: Integrates with Amazon CloudWatch to show metrics like bytes in/out, message rates, and consumer lag.

Updating topic configurations

As your workload requirements evolve, you might need to adjust topic configurations. You can modify various topic settings depending on your cluster type. For example:

  • Retention settings: Adjust retention.ms (time-based) or retention.bytes (size-based) to control how long messages are retained.
  • Message size limits: Modify max.message.bytes to accommodate larger or smaller messages.
  • Compression: Change compression.type to optimize storage and network usage.

Configuration changes take effect immediately for new messages. Existing messages remain subject to the previous configuration until they age out or are consumed.

Deleting topics

Amazon MSK also provides APIs for deleting topics that are no longer in use. Before deleting a topic, verify that:

  • No active producers are writing to the topic
  • All consumers have finished processing messages
  • You have backups if you need to retain the data
  • Downstream applications won’t be impacted

Important: Topic deletion permanently removes all messages in the topic.

Control access with IAM

Beyond streamlining topic operations, you also need appropriate access controls. Access control uses IAM, so you define permissions using the same model that you apply to other AWS resources. Amazon MSK uses a two-level permission model:

  • Resource-level permissions: An IAM policy that enforces which operations the cluster will allow
  • Principal-level permissions: IAM policies attached to Roles or Users that enforce which operations a principal is allowed to perform on a cluster

With this separation, you can control access depending on your organizational needs and access patterns for your cluster. Refer to the IAM permissions documentation for IAM permissions required for topic management for the Amazon MSK cluster.

You can grant your operations team broad access to manage all topics and restrict application teams to manage only their own topics. The permission granularity that you need is available through standard IAM policies. If you’ve already configured IAM permissions for Apache Kafka topics, they work immediately with the new functionality without any migration or reconfiguration.

Here is a sample IAM policy definition that allows Describe Topic API

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Action": [
                "kafka-cluster:Connect"
            ],
            "Resource": [
                "arn:aws:kafka:us-east-1:111111111111:cluster/iam-auth-acl-test/a6b5c6d5-f74f-4dbc-ad14-63fb5e87fe4f-2"
            ]
        },
        {
            "Effect": "Allow",
            "Action": [
                "kafka-cluster:DescribeTopic",
                "kafka-cluster:DescribeTopicDynamicConfiguration"
            ],
            "Resource": [
                "arn:aws:kafka:us-east-1:111111111111:topic/iam-auth-acl-test/a6b5c6d5-f74f-4dbc-ad14-63fb5e87fe4f-2/*"
            ]
        }
    ]
}

This IAM policy grants the necessary permissions to describe Kafka topics in your Amazon MSK cluster. The policy includes three key permissions:

  • kafka-cluster:Connect – Allows connection to the specified MSK cluster
  • kafka-cluster:DescribeTopic – Enables viewing topic details
  • kafka-cluster:DescribeTopicDynamicConfiguration – Enables viewing topic dynamic configuration

The policy is scoped to a specific cluster ARN and applies to all topics within that cluster using the wildcard pattern /*. Replace the placeholder Amazon MSK cluster ARN with your MSK cluster ARN.

Infrastructure as Code

If you manage infrastructure as code (IaC), you can now define topics alongside clusters in your CloudFormation templates:

Resources:
    OrdersTopic:
      Type: AWS::MSK::Topic
      Properties:
        ClusterArn: !GetAtt MyMSKCluster.Arn
        TopicName: orders
        NumPartitions: 6
        ReplicationFactor: 3
        Config:
          retention.ms: "604800000"

This approach brings topic provisioning into your CI/CD pipelines.

Availability and pricing

The new Amazon MSK topic management experience is available today for Standard and Express Amazon MSK clusters using Apache Kafka version 3.6 and above in all AWS Regions where Amazon MSK is offered, at no additional cost.

Cleanup

To avoid incurring additional charges to your AWS account, ensure you delete all resources created during this tutorial, including:

  • Amazon MSK cluster
  • Any Kafka topics created
  • Associated AWS resources (security groups, VPCs, etc., if created specifically for this blog)

Remember to verify that all resources have been successfully removed to prevent ongoing costs.

Conclusion

Topic management has been a persistent pain point for Apache Kafka operations. The new integrated experience in Amazon MSK now reduces operational friction by bringing topic operations into the AWS tools that you use every day. You now have a consistent, streamlined way to handle these operations for all Apache Kafka topics across multiple MSK clusters. This capability reflects our commitment to reducing operational complexity in Apache Kafka. You get the reliability and performance of Apache Kafka without the operational overhead that traditionally comes with it. Your team spends less time on infrastructure maintenance and more time building streaming applications that drive your business forward.

Ready to start streamlining your topic management? Start managing your topics today through the Amazon MSK console or by visiting the Amazon MSK documentation.


About the authors

Swapna Bandla

Swapna is a Senior Streaming Solutions Architect at AWS. With a deep understanding of real-time data processing and analytics, she partners with customers to architect scalable, cloud-native solutions that align with AWS Well-Architected best practices. Swapna is passionate about helping organizations unlock the full potential of their data to drive business value. Beyond her professional pursuits, she cherishes quality time with her family.

Mazrim Mehrtens

Mazrim is a Sr. Specialist Solutions Architect for messaging and streaming workloads. They work with customers to build and support systems that process and analyze terabytes of streaming data in real time, run enterprise Machine Learning pipelines, and create systems to share data across teams seamlessly with varying data toolsets and software stacks.

Judy Huang

Judy is a Senior Product Manager for Amazon Managed Streaming for Apache Kafka (MSK) at AWS. She is passionate about real-time data systems and helping organizations unlock the value of streaming data at scale. Her work focuses on improving how customers manage Kafka infrastructure and building capabilities that make streaming platforms more accessible, resilient, and integrated with the broader data ecosystem.

Securely connect Kafka client applications to your Amazon MSK Serverless cluster from different VPCs and AWS accounts

Post Syndicated from Subham Rakshit original https://aws.amazon.com/blogs/big-data/securely-connect-kafka-client-applications-to-your-amazon-msk-serverless-cluster-from-different-vpcs-and-aws-accounts/

Amazon MSK Serverless is a cluster type for Amazon MSK that you can use to run Apache Kafka without having to manage and scale cluster capacity. It automatically provisions and scales capacity while managing the partitions in your topics, so you can stream data without thinking about right-sizing or scaling clusters. MSK Serverless is fully compatible with Apache Kafka, so you can use any compatible client applications to produce and consume data.

MSK Serverless uses AWS PrivateLink to provide private connectivity up to five virtual private clouds (VPCs) within the same AWS account. However, if you need cross-VPC connectivity beyond five VPCs or cross-account connectivity, you typically need VPC peering or AWS Transit Gateway, as explained in Secure connectivity patterns for Amazon MSK Serverless cross-account access.

Aklivity Zilla Plus for Amazon MSK is a stateless Kafka-native edge proxy that enables authorized Kafka clients deployed across VPCs (even cross-account) to securely connect, publish messages, and subscribe to topics in your MSK Serverless cluster using a custom domain name.

For more details on supporting SASL/SCRAM authentication with a custom domain, see Configure a custom domain name for your Amazon MSK cluster.

In this post, we show you how Kafka clients can use Zilla Plus to securely access your MSK Serverless clusters through Identity and Access Management (IAM) authentication over PrivateLink, from as many different AWS accounts or VPCs as needed. We also show you how the solution provides a way to support a custom domain name for your MSK Serverless cluster.

Secure private access to one MSK Serverless cluster

Network Load Balancers (NLBs) provide a convenient way to define remote connectivity to MSK Serverless clusters from other VPCs. In the following architecture diagram, Zilla Plus is deployed in an auto scaling group, reachable as a target group behind an NLB. Zilla Plus connects to an MSK Serverless cluster through the (rightmost) VPC endpoint associated directly with the MSK Serverless cluster. Zilla Plus is configured to use an AWS Certificate Manager (ACM) wildcard certificate for your custom domain. By creating a Zilla Plus VPC Endpoint Service, you make the MSK Serverless cluster reachable from other VPCs through Zilla Plus.

As shown in the preceding figure, the client VPC has minimal configuration, consisting of a Zilla Plus VPC endpoint to reach the Zilla Plus VPC Endpoint Service, and an Amazon Route 53 local zone mapping your custom domain name to the Zilla Plus VPC endpoint.

How the custom domain works across VPCs for MSK Serverless

When an MSK Serverless cluster is created, it is associated with a bootstrap broker address like this:boot-xxxxxxxx.yy.kafka-serverless.region.amazonaws.com:9098. However, this address is only resolvable within the originating VPC.

To access the cluster from another VPC or account, Kafka clients connect to a custom domain exposed by Zilla Plus, such as boot.my.custom.domain:9098. The Route 53 DNS in the client VPC maps this custom domain to a VPC endpoint (NLB), while the NLB forwards traffic to Zilla Plus, which presents the appropriate ACM wildcard certificate. When a Kafka client needs to bootstrap connectivity to a Kafka cluster (such as an MSK Serverless cluster), the client must follow a two-step discovery process to learn the specific addresses of the brokers in the cluster, so it can then connect to each broker directly as needed.

For example, if the client needs to produce messages to a specific Kafka topic such as my-messages, then the client first uses a bootstrap server address to connect to any broker in the Kafka cluster, requesting topic metadata that includes the address of each broker responsible for storage of messages in the my-messages topic. In the second step, the client connects directly to the corresponding brokers for the my-messages topic to produce messages. The sequence of connection flow between Kafka client and broker is shown below.

When the Kafka client connection for the custom domain bootstrap server arrives at the Zilla Plus VPC NLB, it’s routed to any of the Zilla Plus instances in the target group. Zilla Plus presents the wildcard TLS certificate for the custom domain and completes the TLS handshake before establishing connectivity to the MSK Serverless bootstrap server. Kafka protocol requests flow from the client through Zilla Plus to the MSK Serverless bootstrap server. When the metadata request is made by the Kafka client, Zilla Plus intercepts the metadata response and rewrites the discovered broker addresses advertised to the client, mapping them to the custom domain.

When the Kafka client connections for each individual broker address arrive at Zilla Plus, the broker-specific custom domain address is mapped to the broker-specific MSK Serverless address so that the client connects to the requested broker in the cluster. Even though the MSK Serverless cluster can have any number of advertised broker addresses, the number of instances in the Zilla Plus target group isn’t required to match. Each Zilla Plus instance can relay broker-specific custom domain connectivity for any broker in the MSK Serverless cluster. Because no configuration changes are required at the MSK Serverless cluster to enable the Zilla Plus custom domain mapping, there’s no impact on other Kafka clients already connecting directly to the MSK Serverless cluster using the AWS-generated bootstrap server.

Follow the guided steps in the Aklivity Zilla Plus documentation to deploy this solution using the AWS Cloud Development Kit (AWS CDK). This automates the setup for you, including the client VPC configuration to create the VPC endpoint and Route 53 DNS entries.

After the secure private access and secure private access client scenarios have been deployed successfully, you can verify remote access to the MSK Serverless cluster from any Kafka client using your custom domain bootstrap server.

Secure private access to multiple MSK Serverless clusters

When a Kafka client needs to bootstrap to multiple different custom domain MSK Serverless clusters, the approach described previously keeps the client VPC configuration relatively straightforward.

As shown in the preceding figure, each custom domain has a single Route53-hosted zone wildcard DNS record aliased to the corresponding local VPC endpoint for the corresponding remote MSK Serverless cluster. When the Kafka client performs bootstrap, local DNS resolution for the custom domain bootstrap server hostname routes connectivity to the correct VPC endpoint and the TLS certificate presented validates trust for the custom domain hostname too. Connectivity to individual broker addresses in the same custom domain are routed and trusted in the same way.

Secure private to MSK Serverless clusters through AWS Client VPN

When on-premises Kafka clients need to access an MSK Serverless cluster, the client VPC can be associated with an AWS Client VPN endpoint to connect through AWS Client VPN, as shown in the following figure.

By configuring the AWS Client VPN endpoint to use the client VPC DNS server, the AWS Client VPN connections will automatically resolve the custom domain bootstrap server hostname and connect through Zilla Plus to MSK Serverless.

Conclusion

You can use Amazon MSK Serverless clusters to run Apache Kafka without having to manage and scale cluster capacity. With Zilla Plus for Amazon MSK, you can access one or more of your Amazon MSK Serverless clusters from one or more remote client VPCs using a custom domain for each MSK Serverless cluster. The remote client VPCs can also belong to different AWS accounts, while still enforcing fine-grained AWS Identity and Access Management (IAM) authorization for topics and consumer groups. On-premises clients can also use this approach to connect to an MSK Serverless cluster through AWS Client VPN from a different AWS account.

Zilla Plus requires no configuration changes to your MSK Serverless cluster, so adding a custom domain for remote Kafka clients has no impact on existing Kafka clients—including MSK Connect, MSK Replicator, or other MSK Integrations—that connect directly to your MSK Serverless cluster.

Learn more about Zilla Plus for Amazon MSK on AWS Marketplace and the Aklivity Zilla Plus documentation.


About the authors

Subham Rakshit

Subham Rakshit

Subham is a Senior Streaming Solutions Architect for Analytics at AWS based in the UK. He works with customers to design and build streaming architectures so they can get value from analyzing their streaming data. His two little daughters keep him occupied most of the time outside work, and he loves solving jigsaw puzzles with them.

John Fallows

John Fallows

John is the Chief Technical Officer at Aklivity based in California, USA. He is a regular contributor to the Zilla open-source project, connecting web, mobile and IoT applications to Apache Kafka to help developers fully unlock the power of their event-driven architectures.

Simplifying Kafka operations with Amazon MSK Express brokers

Post Syndicated from Mazrim Mehrtens original https://aws.amazon.com/blogs/big-data/simplifying-kafka-operations-with-amazon-msk-express-brokers/

In this post, we show you how Amazon Managed Streaming for Apache Kafka (Amazon MSK) Express brokers brokers streamline the end-to-end activities for Kafka administration. Apache Kafka has become the de facto standard for real-time data streaming, powering mission-critical applications across industries worldwide. Its popularity stems from its ability to handle high-throughput, fault-tolerant data pipelines at scale. Given its central role in modern data architectures, managing Apache Kafka with high resilience and reliability is essential for business success.

To maintain this level of resilience, administrators need to handle several important operational tasks. Apache Kafka is a distributed stateful system, whose state management requires constant communication and data movement in dynamic cloud environments. Administrators need to carefully size clusters by calculating complex compute, storage, and network requirements. They must provision storage volumes upfront and monitor utilization constantly to avoid disruptions. When workloads grow, scaling the cluster requires hours or days of effort using multiple tools to provision capacity and rebalance load.

With these operational requirements in mind, many administrators ask: is there an easier way to manage Apache Kafka at scale while maintaining the high resilience their applications demand?

Amazon MSK Express addresses these challenges directly. In this post, we show you how MSK Express brokers streamline the end-to-end activities for Kafka administration, including:

  • Sizing Kafka clusters for optimal performance and cost
  • Scaling cluster storage up and down with workload changes
  • Scaling cluster compute in and out over time
  • Monitoring cluster health
  • Managing cluster security
  • Ensuring high availability with fast and automatic broker recovery

What are Amazon MSK Express brokers?

Amazon MSK Express brokers are a transformative breakthrough for customers needing high-throughput Kafka clusters that scale faster and cost less. Express brokers reimagine Kafka’s compute and storage, decoupling to unlock performance and elasticity benefits. Express brokers deliver performance improvements that directly impact your operations:

  • Up to 3x more throughput per broker, allowing you to handle more data with fewer resources and lower costs
  • Rebalance partitions across brokers 180x faster, reducing scaling from hours to minutes
  • Scale up to 20x faster, enabling you to respond to demand spikes without lengthy planning cycles
  • Recover 90% quicker compared to standard Apache Kafka brokers, minimizing workload disruption and maintaining business continuity

To learn more about the technical details, see Express brokers for Amazon MSK: Turbo-charged Kafka scaling with up to 20 times faster performance. For a comprehensive overview of Express broker capabilities, see the MSK Express brokers documentation.

Let’s explore how MSK Express brokers simplify Apache Kafka management.

Sizing an Express cluster

Sizing a traditional Apache Kafka cluster is complex. Working backwards from your ingress and egress load, you need to consider every dimension of your cluster compute, storage, and network limitations. Each node must be carefully sized to handle:

  • Ingress and egress traffic from your clients
  • Internal Kafka operations like replication and rebalancing (the process of redistributing partitions across brokers to maintain balance)
  • High availability with node and Availability Zone failures
  • Client operations like backfill procedures when reading historical data

These activities impact your cluster storage I/O limits, network ingress/egress limits, and CPU and memory constraints. Beyond this, you need to consider the number of partitions required and determine whether your cluster can scale to handle partition management for your use case.

MSK Express brokers simplify this calculus. Rather than considering these complex variables, you can focus on what matters:

  • Your ingress throughput
  • Your egress throughput
  • Your partition needs

MSK documents the Express broker throughput throttle and partition limits by broker size. MSK pre-calculates these to consider all cluster limits. They include multi-Availability Zone high availability to handle rare events like node failures or AZ impairment.

Notice we did not discuss storage in sizing an Express cluster. That is because storage in Express scales nearly infinitely. You pay for storage as you go rather than sizing storage up front.

Scaling Express cluster storage

With sizing simplified by focusing on throughput and partitions, storage management becomes the next operational consideration.

Normally, Apache Kafka clusters need storage volumes pre-provisioned to handle all retained data. You must allocate all storage up-front and pay for that storage no matter what your actual data retention is.

Example: If you store 7 days of data at 1 MB/sec ingress, that’s 600+ GB of storage. This does not include data replication across nodes and buffers for growth and workload variability. This workload requires over 3 TB of storage, allocated up-front, to handle replicas and storage buffers.

As your workload evolves, careful monitoring of storage utilization becomes essential. Adding storage capacity prevents workload disruptions. Often, you cannot reclaim this storage. Once you increase the volume size, you continue paying for additional storage even if your workload scales down and no longer requires additional capacity.

With Express brokers, there is no need for sizing and provisioning storage volumes. You pay for what you use with no provisioning: the data ingested to the cluster and data stored in the cluster per-GB-per-hour. All data stored in the cluster is replicated across 3 Availability Zones for high availability. This pay-as-you-go model eliminates wasted capacity costs and reduces your total infrastructure spend.

  • As workloads scale up, the cluster uses more storage with no changes needed from you
  • When workloads scale down, the cluster uses less storage, reducing storage charges automatically
  • Storage management for Apache Kafka becomes simpler with Express. You focus on ensuring that your per-topic retention is right-sized for each use case. That is the only consideration. Once you set up topic retention, MSK Express automatically manages and cost-optimizes storage on your behalf.

Storage management in MSK Express brokers is far simpler than in a traditional Apache Kafka cluster. So is scaling the compute capacity for an Express-based cluster.

Scaling Express cluster compute

Just as storage scales automatically with your workload, compute capacity can also adapt to changing demands.

As your workload grows and changes, you may find that you exceed your initial sizing estimates. For a traditional Apache Kafka cluster, scaling the cluster capacity is a significant event. Scaling takes effort to provision capacity and rebalance load, it requires using multiple tools to manage the scaling process (compute, storage, DNS, rebalancing, client configs, and more). The scaling process can take hours or days to complete, which can exacerbate application impact. This means you need to plan well ahead to ensure your Kafka cluster is prepared for any load changes.

With MSK Express clusters, this process becomes much simpler and requires little to no upfront planning. It has near zero disruption to your existing workload, allowing your team to focus on building features rather than managing infrastructure.

To scale up an MSK Express cluster, you simply add brokers to the cluster. Once new brokers come online, Express Intelligent Rebalancing automatically rebalances topic partitions to the new nodes. Thanks to the Express storage architecture, the new nodes automatically have almost all the data they need. There is no significant inter-broker communication for rebalancing. This causes no disruption to existing brokers.

The cluster then elects new broker leaders for each partition, enabling producers to direct traffic to the new nodes. The same applies to consumer groups.

Express broker DNS design keeps this in mind. Express broker connection strings abstract away from the nodes themselves. Clients connect to the active broker nodes with one connection string. No changes to DNS, load balancing, or client configurations are needed.

Deciding when to scale in an Express cluster is also simpler than in a traditional Apache Kafka cluster. The simplified Express architecture means less to monitor and manage for long-term cluster operations.

Monitoring Express clusters

With simplified scaling decisions comes simplified monitoring. Express brokers reduce the number of metrics you need to track for cluster health. The below image demonstrates a dashboard which highlights the key metrics for monitoring MSK Express broker health.

Dashboard with key Amazon MSK Express brokers metrics

In a traditional Apache Kafka cluster, you need to consider dozens of metrics to understand overall cluster health. Express brokers simplify this operational process. They highlight ingress and egress throughput as two critical metrics for workload sizing and scaling. This streamlined monitoring approach reduces the expertise required to operate Kafka clusters and allows smaller teams to manage larger deployments effectively.

Other factors, like poorly designed clients, can incur additional overhead on a cluster. This can cause symptoms such as high CPU utilization without high ingress throughput. It is still important to monitor a variety of metrics with MSK Express brokers.

For Express brokers, the following table shows the critical metrics you must monitor and alert on for cluster health:

Metric Name Description Recommended Alarm
BytesInPerSec Ingress throughput to the cluster When > broker limit for > 5 minutes
BytesOutPerSec Egress throughput to the cluster When > broker limit for > 5 minutes
CpuUser + CpuSystem CPU utilization percentage When greater than 60% for 15 minutes
NetworkProcessorAvgIdlePercent Network processor thread idle time When less than 0.5 for > 5 minutes
RequestHandlerAvgIdlePercent Request processor thread idle time When less than 0.4 for > 15 minutes
FetchThrottleByteRate Consumer fetch throttling rate When < 0 for > 15 minutes
ProduceThrottleByteRate Producer ingress throttling rate When < 0 for > 15 minutes

For more information on monitoring Amazon MSK, see Monitoring Amazon MSK with Amazon CloudWatch.

Managing Express cluster access

Beyond monitoring, cluster management is another area where MSK Express brokers reduce operational complexity.

Express brokers simplify the internal management of Kafka clusters. In a traditional Kafka environment, you use schemes like SASL/SCRAM (username and password-based authentication) or mutual TLS (certificate-based authentication) for client authentication. Once authenticated, you configure complex Kafka ACLs (Access Control Lists—permissions that define who can access which topics) inside the Kafka cluster to authorize client access to topics and data.

These paradigms require you to manage all topics, authentication, and authorization inside Apache Kafka. This includes credential management, rotation, and other operational activities surrounding cluster access.

MSK simplifies this process by integrating with AWS Identity and Access Management (IAM) for access control. Clients can use IAM Roles that clearly specify cluster access boundaries. They also provide topic-level authorization to read and write data to a cluster with Kafka APIs.

Finally, clients can use MSK APIs to directly manage Kafka cluster configurations and Kafka topics, including creating new topics, updating topic configurations and partition counts, and deleting topics. Configurations and topics can be managed with the AWS Console, AWS CLI, and AWS SDK. For more information, refer to Amazon MSK simplifies Kafka topic management with new APIs and console integration.

You can focus only on your existing enterprise standards for IAM access controls, and your existing AWS CloudFormation and AWS CDK automation to manage your cluster with Infrastructure as Code (IaC). This integration reduces the operational overhead of cluster management and accelerates your time to production by leveraging existing security infrastructure.

MSK also supports using SASL/SCRAM and mutual TLS authentication modes alongside IAM access control. This gives you the flexibility to authorize applications outside of AWS. You can also provide access to legacy applications without the need for code changes.

For more information, see IAM access control for Amazon MSK and Security in Amazon MSK.

Building highly available Express brokers

With security simplified through IAM integration, high availability is the final piece of the operational puzzle.

Many of the same considerations we discussed in scaling Express cluster compute align with high availability considerations for MSK Express brokers.

Based on internal testing, MSK Express broker storage improvements enable faster recovery when broker nodes fail—90% faster than standard brokers. The new node can simply start up with almost no disruption to the rest of the cluster without needing to perform significant rebalancing. This contrasts with standard Kafka clusters, where the cluster needs to rebalance partitions to new nodes after recovery.

In addition to these improvements, MSK Express brokers are highly available by default. The service manages critical cluster and topic configurations for high availability and performance on your behalf. This eliminates the need for managing most cluster configurations.

Express fully manages configurations like min.insync.replicas, num.io.threads, and others described in Express brokers’ read-only configurations. This gives you a highly available and performant cluster out of the box.

You no longer need to worry about most cluster-level configurations of an Apache Kafka cluster. You can simply:

  • Start an MSK Express cluster
  • Configure topics and retention
  • Proceed without the fine tuning normally needed to ensure a highly available cluster

Conclusion

In this post, we showed how MSK Express brokers simplify cluster operations for Apache Kafka clusters. They lower the Total Cost of Ownership (TCO) of running an Apache Kafka cluster by simplifying sizing, storage management, compute management, high availability, and access control, while providing high performance, reliability, and cost-efficiency. These simplifications reduce the specialized expertise needed for cluster administration and accelerate your deployment timeline.

With this in mind, we recommend MSK Express brokers for almost all MSK workloads. If you are starting out with a new Kafka cluster or optimizing an existing one, MSK Express brokers provide a strong combination of simplicity, performance, and cost-efficiency.

Ready to simplify your Kafka operations? Get started using Amazon MSK to create your first Express cluster today. You can provision a fully managed, highly available Kafka cluster in minutes and start experiencing the operational benefits immediately. For pricing details, see Amazon MSK pricing.

For comprehensive information about Amazon MSK capabilities and features, visit the Amazon MSK product page and the Amazon MSK Developer Guide.


About the authors

Mazrim Mehrtens

Mazrim Mehrtens

Mazrim is a Sr. Specialist Solutions Architect for messaging and streaming workloads. Mazrim works with customers to build and support systems that process and analyze terabytes of streaming data in real time, run enterprise Machine Learning pipelines, and create systems to share data across teams seamlessly with varying data toolsets and software stacks.

Sai Maddali

Sai Maddali

Sai is a Senior Manager Product Management at AWS who leads the product team for Amazon MSK. He is passionate about understanding customer needs, and using technology to deliver services that empowers customers to build innovative applications. Besides work, he enjoys traveling, cooking, and running.