Cloudflare helps verify the security of end-to-end encrypted messages by auditing key transparency for WhatsApp

Post Syndicated from Thibault Meunier original https://blog.cloudflare.com/key-transparency

Chances are good that today you’ve sent a message through an end-to-end encrypted (E2EE) messaging app such as WhatsApp, Signal, or iMessage. While we often take the privacy of these conversations for granted, they in fact rely on decades of research, testing, and standardization efforts, the foundation of which is a public-private key exchange. There is, however, an oft-overlooked implicit trust inherent in this model: that the messaging app infrastructure is distributing the public keys of all of its users correctly.

Here’s an example: if Joe and Alice are messaging each other on WhatsApp, Joe uses Alice’s phone number to retrieve Alice’s public key from the WhatsApp database, and Alice receives Joe’s public key. Their messages are then encrypted using this key exchange, so that no one — even WhatsApp — can see the contents of their messages besides Alice and Joe themselves. However, in the unlikely situation where an attacker, Bob, manages to register a different public key in WhatsApp’s database, Joe would try to message Alice but unknowingly be messaging Bob instead. And while this threat is most salient for journalists, activists, and those most vulnerable to cyber attacks, we believe that protecting the privacy and integrity of end-to-end encrypted conversations is for everyone.

There are several methods that end-to-end encrypted messaging apps have deployed thus far to protect the integrity of public key distribution, the most common of which is to do an in-person verification of the QR code fingerprint of your public key (WhatsApp and Signal both have a version of this). As you can imagine, this experience is inconvenient and unwieldy, especially as your number of contacts and group chats increase.

Over the past few years, there have been significant developments in this area of cryptography, and WhatsApp has paved the way with their Key Transparency announcement. But as an independent third party, Cloudflare can provide stronger reassurance: that’s why we’re excited to announce that we’re now verifying WhatsApp’s Key Transparency audit proofs. 

Auditing: the next frontier of encryption 

We didn’t build this in a vacuum: similar to how the web and messaging apps became encrypted over time, we see auditing public key infrastructure as the next logical step in securing Internet infrastructure. This solution builds upon learnings from Certificate Transparency and Binary Transparency, which share some of the underlying data structure and cryptographic techniques, and we’re excited about the formation of a working group at the IETF to make multi-party operation of Key Transparency-like systems tractable for a broader set of use cases. 

We see our role here as a pioneer of a real world deployment of this auditing infrastructure, working through and sharing the operational challenges of operating a system that is critical for a messaging app used by billions of people around the world.   

We’ve also done this before — in 2022, Cloudflare announced Code Verify, a partnership in which we verify that the code delivered in the browser for WhatsApp Web has not been tampered with. When users run WhatsApp in their browser, the WhatsApp Code Verify extension compares a hash of the code that is executing in the browser with the hash that Cloudflare has of the codebase, enabling WhatsApp web users to easily see whether the code that is executing is the code that was publicly committed to. 
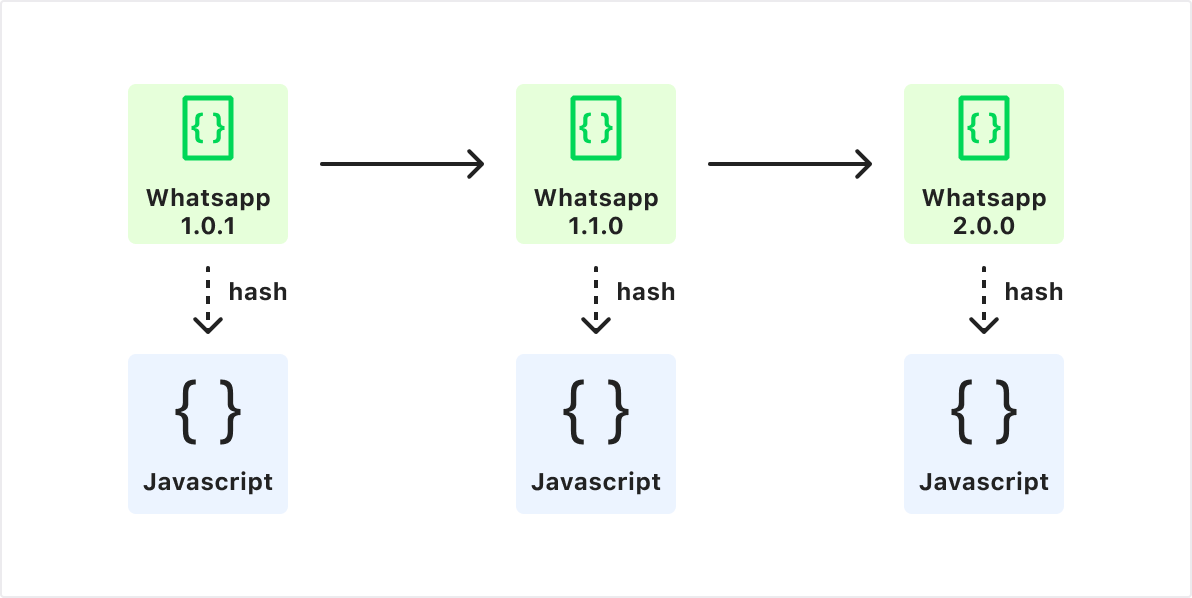
In Code Verify, Cloudflare builds a non-mutable chain associating the WhatsApp version with the hash of its code.

Cloudflare’s role in Key Transparency is similar in that we are checking that a tree-based directory of public keys (more on this later) has been constructed correctly, and has been done so consistently over time.

How Key Transparency works

The architectural foundation of Key Transparency is the Auditable Key Directory (AKD): a tree-shaped data structure, constructed and maintained by WhatsApp, in which the nodes contain hashed contact details of each user. We’ll explain the basics here but if you’re interested in learning more, check out the SEEMless and Parakeet papers.

The AKD tree is constructed by building a binary tree, each parent node of which is a hash of each of its left and right child nodes:
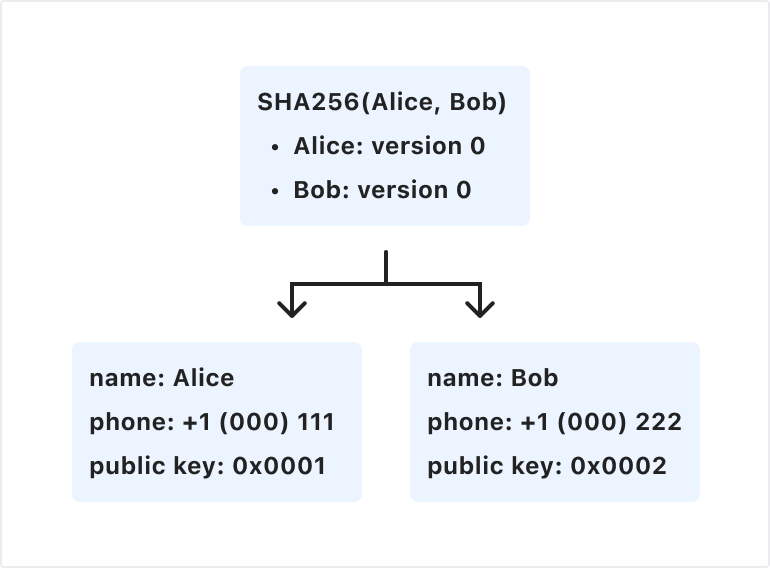
Each child node on the tree contains contact and public key details for a user (shown here for illustrative purposes). In reality, Cloudflare only sees a hash of each node rather than Alice and Bob’s contact info in plaintext.

An epoch describes a specific version of the tree at a given moment in time, identified by its root node. Using a structure similar to Code Verify, the WhatsApp Log stores each root node hash as part of an append-only time structure of updates.
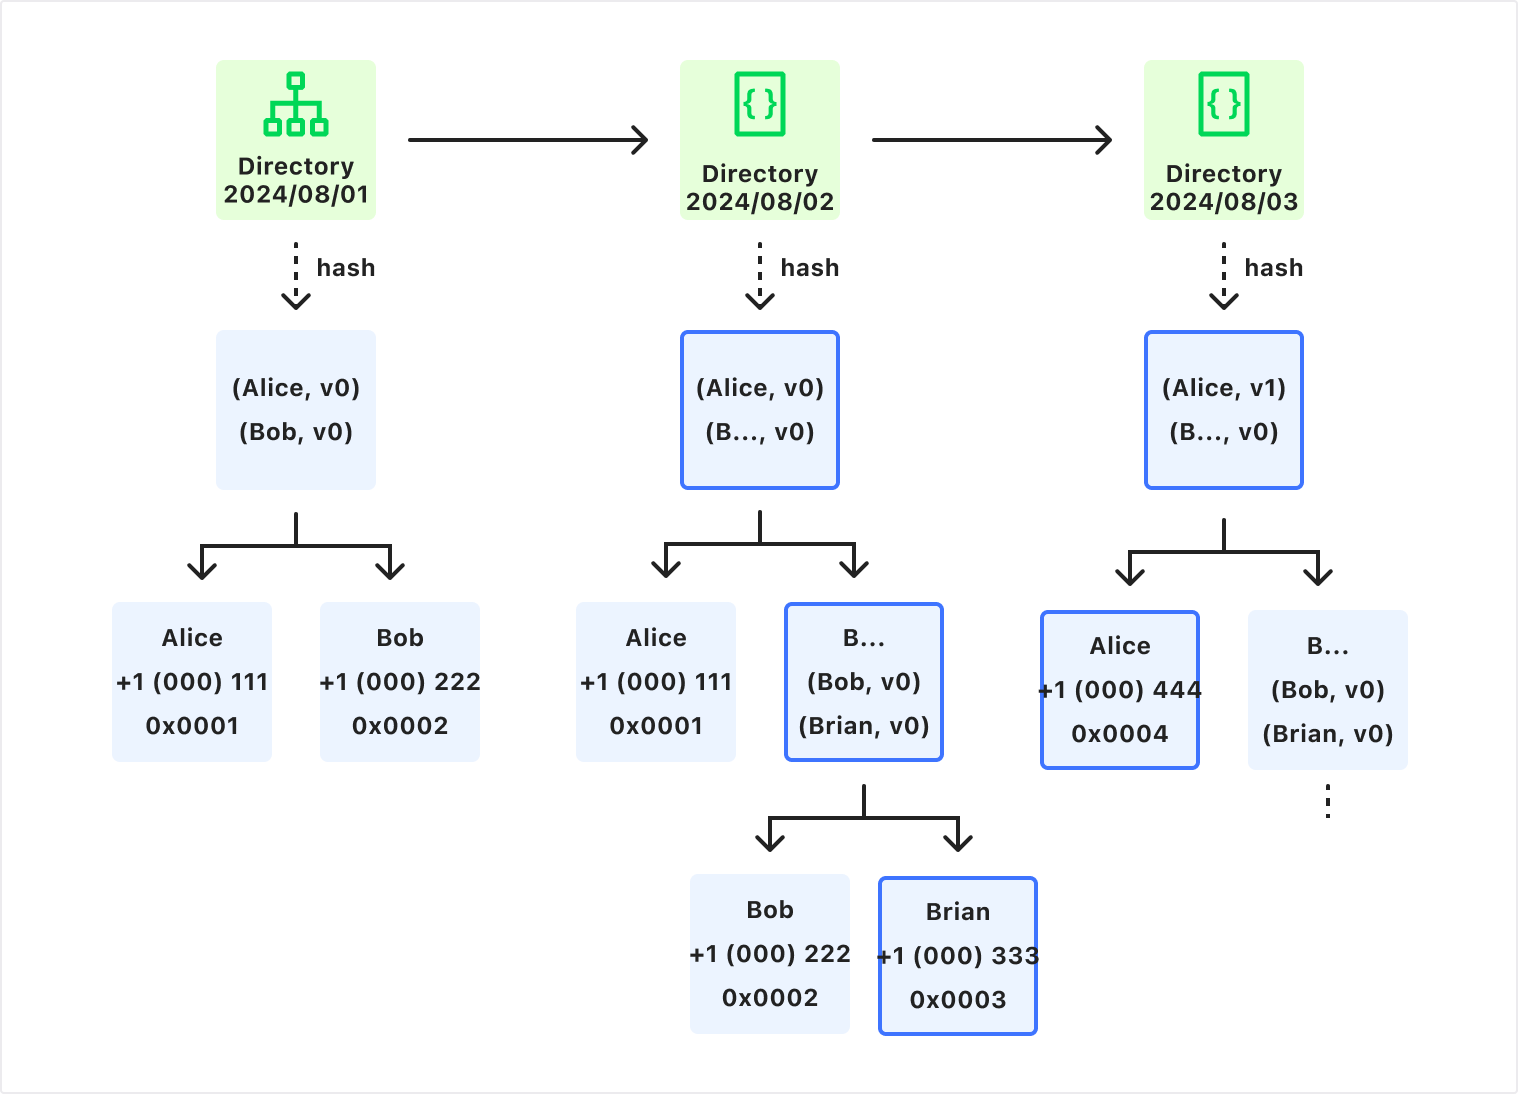
What kind of changes are valid to be included in a given epoch? When a new person, Brian, joins WhatsApp, WhatsApp inserts a new “B” node in the AKD tree, and a new epoch. If Alice loses her phone and rotates her key, her “version” is updated to v1 in the next update.  

How we built the Auditor on Cloudflare Workers 

The role of the Auditor is to provide two main guarantees: that epochs are globally unique, and that they are valid. They are, however, quite different: global uniqueness requires consistency on whether an epoch and its associated root hash has been seen, while validity is a matter of computation — is the transition from the previous epoch to the current one a correct tree transformation?

Timestamping service
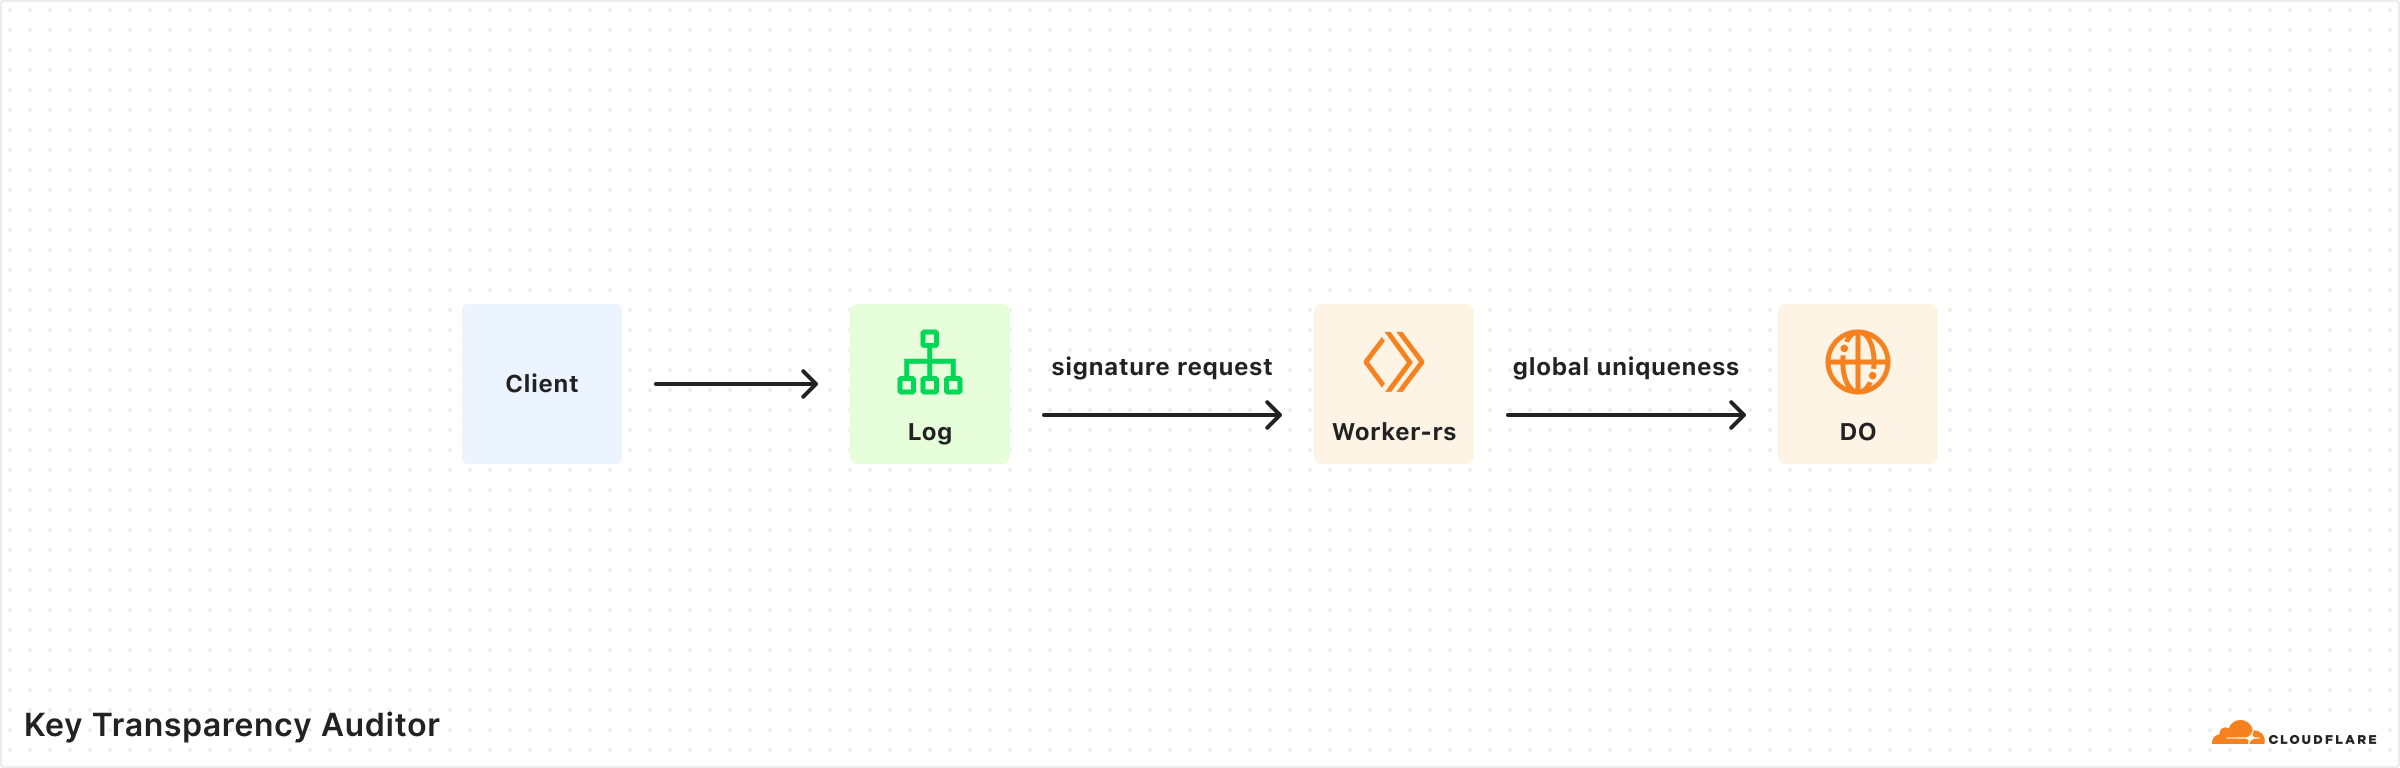
Timestamping service architecture (Cloudflare Workers in Rust, using a Durable Object for storage)

At regular intervals, the WhatsApp Log puts all new updates into the tree, and cuts a new epoch in the format “{counter}/{previous}/{current}”. The counter is a number, whereby “previous” is a hexadecimal encoded hash of the previous tree root, and “current” is a hexadecimal encoded hash for the new tree root. As a shorthand, epochs can be referred to by their counter only.

Here’s an example:

1001/d0bbf29c48716f26a951ae2a244eb1d070ee38865c29c8ad8174e8904e3cdc1a/e1006114485e8f0bbe2464e0ebac77af37bce76851745592e8dd5991ff2cd411

Once an epoch is constructed, the WhatsApp Log sends it to the Auditor for cross-signing, to ensure it has only been seen once. The Auditor adds a timestamp as to when this new epoch has been seen. Cloudflare’s Auditor uses a Durable Object for every epoch to create their timestamp. This guarantees the global uniqueness of an epoch, and the possibility of replay in the event the WhatsApp Log experiences an outage or is distributed across multiple locations. WhatsApp’s Log is expected to produce new epochs at regular intervals, given this constrains the propagation of public key updates seen by their users. Therefore, Cloudflare Auditor does not have to keep the durable object state forever. Once replay and consistency have been accounted for, this state is cleared. This is done after a month, thanks to durable object alarms.

Additional checks are performed by the service, such as checking that the epochs are consecutive, or that their digest is unique. This enforces a chain of epochs and their associated digests, provided by the WhatsApp Log and signed by the Auditor, providing a consistent view for all to see.

We decided to write this service in Rust because Workers rely on cloudflare/workers-rs bindings, and the auditable key directory library is also in Rust (facebook/akd).

Tree validation service

With the timestamping service above, WhatsApp users (as well as their Log) have assurance that epochs are transparent. WhatsApp’s directory can be audited at any point in time, and if it were to be tampered with by WhatsApp or an intermediary, the WhatsApp Log can be held accountable for it.

Epochs and their digests are only representations of their underlying key directory. To fully audit the directory, the transition from the previous digest to a current digest has to be validated. To perform validation, we need to run the epoch validation method. Specifically, we want to run verify_consecutive_append_only on every epoch constructed by the Log. The size of an epoch varies with the number of updates it contains, and therefore the number of associated nodes in the tree to construct as well. While Workers are able to run such validation for a small number of updates, this is a compute-intensive task. Therefore, still leveraging the same Rust codebase, the Auditor leverages a container that only performs the tree construction and validation. The Auditor retrieves the updates for a given epoch, copies them into its own R2 bucket, and delegates the validation to a container running on Cloudflare. Once validated, the epoch is marked as verified.
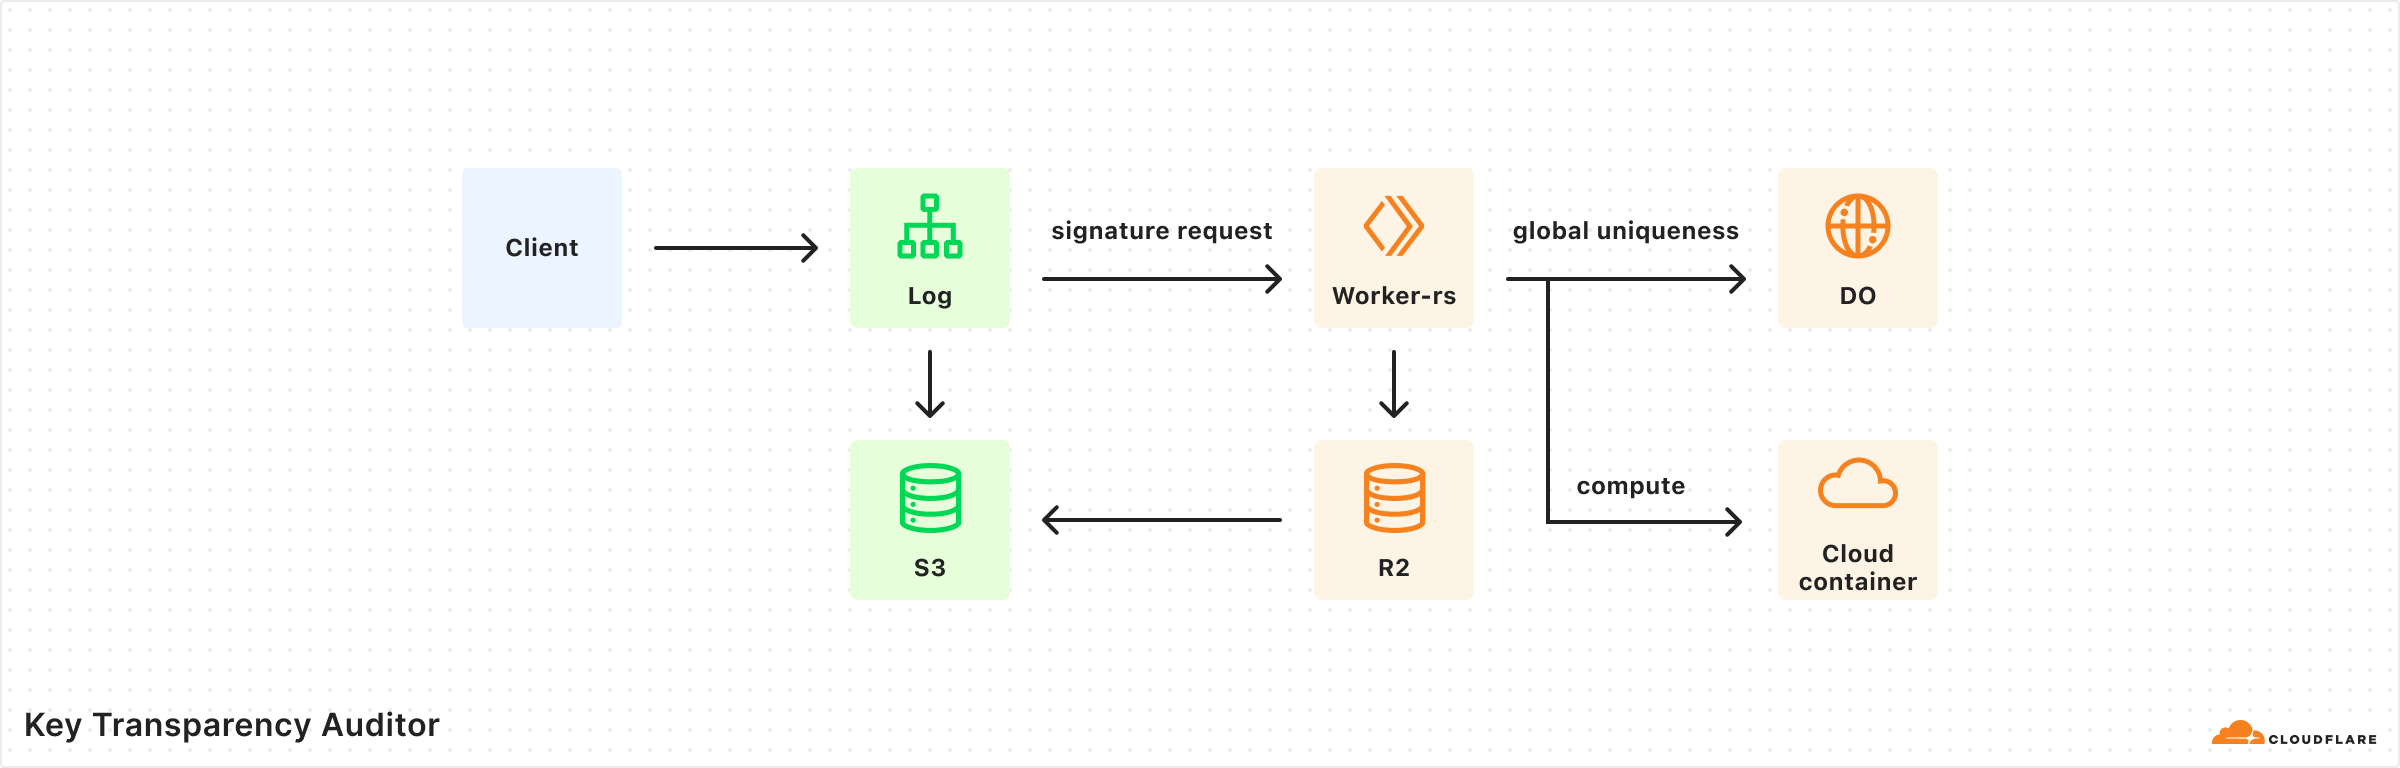
Architecture for Cloudflare’s Plexi Auditor. The proof verification and signatures stored do not contain personally identifiable information such as your phone number, public key, or other metadata tied to your WhatsApp account.

This decouples global uniqueness requirements and epoch validation, which happens at two distinct times. It allows the validation to take more time, and not be latency sensitive.

How can I verify Cloudflare has signed an epoch?

Anyone can perform audit proof verification — the proofs are publicly available — but Cloudflare will be doing so automatically and publicly to make the results accessible to all. Verify that Cloudflare’s signature matches WhatsApp’s by visiting our Key Transparency website, or via our command line tool.

To use our command line tool, you’ll need to download the plexi client. It helps construct data structures which are used for signatures, and requires you to have git and cargo installed.

cargo install plexi

With the client installed, let’s now check the audit proofs for WhatsApp namespace: whatsapp.key-transparency.v1. Plexi Auditor is represented by one public key, which can verify and vouch for multiple Logs with their own dedicated “namespace.” To validate an epoch, such as epoch 458298 (the epoch at which the log decided to start sharing data), you can run the following command:

plexi audit --remote-url 'https://akd-auditor.cloudflare.com' --namespace 'whatsapp.key-transparency.v1' --long
Namespace
  Name              	: whatsapp.key-transparency.v1
  Ciphersuite       	: ed25519(protobuf)

Signature (2024-09-23T16:53:45Z)
  Epoch height      	: 489193
  Epoch digest      	: cbe5097ae832a3ae51ad866104ffd4aa1f7479e873fd18df9cb96a02fc91ebfe
  Signature         	: fe94973e19da826487b637c019d3ce52f0c08093ada00b4fe6563e2f8117b4345121342bc33aae249be47979dfe704478e2c18aed86e674df9f934b718949c08
  Signature verification: success
  Proof verification	: success

Interested in having Cloudflare audit your public key infrastructure?

At the end of the day, security threats shouldn’t become usability problems — everyday messaging app users shouldn’t have to worry about whether the public keys of the people they’re talking to have been compromised. In the same way that certificate transparency is now built into the issuance and use of digital certificates to encrypt web traffic, we think that public key transparency and auditing should be built into end-to-end encrypted systems by default, so that users never have to do manual QR code verification again.

We built our auditing service to be general purpose, reliable, and fast, and WhatsApp’s Key Transparency is just the first of several use cases it will be used for – Cloudflare is interested in helping audit the delivery of code binaries and integrity of all types of end-to-end encrypted infrastructure. If your company or organization is interested in working with us, you can reach out to us here.
Three Recommendations for Creating a Risk-Based Detection and Response Program

Post Syndicated from Rapid7 original https://blog.rapid7.com/2024/09/24/three-recommendations-for-creating-a-risk-based-detection-and-response-program/

Three Recommendations for Creating a Risk-Based Detection and Response Program

It should come as little surprise to most security professionals that keeping pace with the evolution of threat actors has become harder and harder. Maintaining visibility into the threat landscape and on top of external risk vectors is more than a matter of incorporating more point solutions. It takes a concerted risk-based approach, where the tools you choose are just one leg of the tripod.

In a report released earlier this summer, Gartner analysts offer three recommendations for fostering an environment of risk-based threat detection, investigation, and response that includes a deeper understanding of your organization’s risk profile by more than just the security team. Below are our three main takeaways from the Gartner® 3 Ways to Apply a Risk-Based Approach to Threat Detection, Investigation, and Response.

Takeaway 1: Better alignment and clearer objectives

The need to break silos between teams is a time-honored proposition that holds even more weight now than it ever has. Gartner suggests creating a quorum of business leaders from across the entire organization to be read into the state of your security and the needs going forward. Prioritize accurate and regular reporting of security metrics to build trust and create a consistent atmosphere of effective transparency. This group should be diverse, with decision makers and specialists from core departments. According to Gartner, the goal should be to:

“Allow the business to be part of the conversation and therefore champions of the capability, elevating the security program to a business function rather than an I&O underpinning.”

Takeaway 2: Integrated risk context

Giving incident responders as much information (and the right information) they need to quickly and efficiently respond to threats requires a complex layering of risk information that includes prioritization for the businesses key assets. Gartner recommends the use of cyber-risk information elements directly implemented into an IR program, layering in asset-based and business-risk information that gives responders the context they require to appropriately triage what can often be a large volume of data.

Gartner says:

“Incident responders should have as much information at their disposal as needed to be effective at finding a needle in a haystack.”

Takeaway 3: Fully enriched business context from jump

Too much information can often be as detrimental to a security team as too little. SecOps needs to have access to the right information in the most efficient way possible in order to find the signal through the noise. Gartner recommends reducing investigative delays through enriched information complete with business context (see, they are all connected). This transparency can be accomplished in part through SIEM, CAASM, and threat intelligence tools and a robust vulnerability management program, but it is worth noting that Gartner prioritizes providing the right information, not the most information; hence, utilizing the right tools.

All three of these recommendations combine to create a risk-based approach to detection, investigation, and response that Gartner says: “…organizations can expect to create measurable efficiency gains in threat detection and increase their ability to respond to threats in a timely manner.”

The Gartner® 3 Ways to Apply a Risk-Based Approach to Threat Detection, Investigation, and Response, report goes into even greater detail on the best approaches for implementing a risk-based approach to D&R.

Download the report here.

Gartner, 3 Ways to Apply a Risk-Based Approach to Threat Detection, Investigation and

Response, Jonathan Nunez ,  Pete Shoard , 10 July 2024.

GARTNER is a registered trademark and service mark of Gartner, Inc. and/or its affiliates in the

U.S. and internationally and is used herein with permission. All rights reserved.

[$] Committing to Rust in the kernel

Post Syndicated from corbet original https://lwn.net/Articles/991062/

The project to enable the writing of kernel code in Rust has been underway
for several years, and each kernel release includes more Rust code. Even
so, some developers have expressed frustration at the time it takes to get
new functionality merged, and an air of uncertainty still hangs over
the project. At the 2024 Maintainers Summit, Miguel Ojeda led a discussion
on the status of Rust in the kernel and whether the time had come to stop
considering it an experimental project. There were not answers to all of the
questions, but it seems clear that Rust in the kernel will continue
steaming ahead.

Security updates for Tuesday

Post Syndicated from corbet original https://lwn.net/Articles/991492/

Security updates have been issued by Gentoo (GCC, Hunspell, Tor, and ZNC), SUSE (apr-devel, cargo-c, chromedriver, firefox, kernel, libecpg6, libmfx, onefetch, postgresql12, postgresql13, postgresql14, postgresql15, postgresql16, python310-azure-identity, python39, qemu, rage-encryption, stgit, and system-user-zabbix), and Ubuntu (kernel, linux-ibm-5.15, linux-oracle-5.15, linux-xilinx-zynqmp, linux-lowlatency, linux-lowlatency-hwe-5.15, linux-raspi, and py7zr).

Israel’s Pager Attacks and Supply Chain Vulnerabilities

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/09/israels-pager-attacks.html

Israel’s brazen attacks on Hezbollah last week, in which hundreds of pagers and two-way radios exploded and killed at least 37 people, graphically illustrated a threat that cybersecurity experts have been warning about for years: Our international supply chains for computerized equipment leave us vulnerable. And we have no good means to defend ourselves.

Though the deadly operations were stunning, none of the elements used to carry them out were particularly new. The tactics employed by Israel, which has neither confirmed nor denied any role, to hijack an international supply chain and embed plastic explosives in Hezbollah devices have been used for years. What’s new is that Israel put them together in such a devastating and extravagantly public fashion, bringing into stark relief what the future of great power competition will look like—in peacetime, wartime and the ever expanding gray zone in between.

The targets won’t be just terrorists. Our computers are vulnerable, and increasingly so are our cars, our refrigerators, our home thermostats and many other useful things in our orbits. Targets are everywhere.

The core component of the operation, implanting plastic explosives in pagers and radios, has been a terrorist risk since Richard Reid, the so-called shoe bomber, tried to ignite some on an airplane in 2001. That’s what all of those airport scanners are designed to detect—both the ones you see at security checkpoints and the ones that later scan your luggage. Even a small amount can do an impressive degree of damage.

The second component, assassination by personal device, isn’t new, either. Israel used this tactic against a Hamas bomb maker in 1996 and a Fatah activist in 2000. Both were killed by remotely detonated booby-trapped cellphones.

The final and more logistically complex piece of Israel’s plan, attacking an international supply chain to compromise equipment at scale, is something that the United States has done, though for different purposes. The National Security Agency has intercepted communications equipment in transit and modified it not for destructive purposes but for eavesdropping. We know from an Edward Snowden document that the agency did this to a Cisco router destined for a Syrian telecommunications company. Presumably, this wasn’t the agency’s only operation of this type.

Creating a front company to fool victims isn’t even a new twist. Israel reportedly created a shell company to produce and sell explosive-laden devices to Hezbollah. In 2019 the FBI created a company that sold supposedly secure cellphones to criminals—not to assassinate them but to eavesdrop on and then arrest them.

The bottom line: Our supply chains are vulnerable, which means that we are vulnerable. Any individual, country or group that interacts with a high-tech supply chain can subvert the equipment passing through it. It can be subverted to eavesdrop. It can be subverted to degrade or fail on command. And although it’s harder, it can be subverted to kill.

Personal devices connected to the internet—and countries where they are in high use, such as the United States—are especially at risk. In 2007 the Idaho National Laboratory demonstrated that a cyberattack could cause a high-voltage generator to explode. In 2010 a computer virus believed to have been developed by the United States and Israel destroyed centrifuges at an Iranian nuclear facility. A 2017 dump of CIA documents included statements about the possibility of remotely hacking cars, which WikiLeaks asserted could be used to carry out “nearly undetectable assassinations.” This isn’t just theoretical: In 2015 a Wired reporter allowed hackers to remotely take over his car while he was driving it. They disabled the engine while he was on a highway.

The world has already begun to adjust to this threat. Many countries are increasingly wary of buying communications equipment from countries they don’t trust. The United States and others are banning large routers from the Chinese company Huawei because we fear that they could be used for eavesdropping and—even worse—disabled remotely in a time of escalating hostilities. In 2019 there was a minor panic over Chinese-made subway cars that could have been modified to eavesdrop on their riders.

It’s not just finished equipment that is under the scanner. More than a decade ago, the US military investigated the security risks of using Chinese parts in its equipment. In 2018 a Bloomberg report revealed US investigators had accused China of modifying computer chips to steal information.

It’s not obvious how to defend against these and similar attacks. Our high-tech supply chains are complex and international. It didn’t raise any red flags to Hezbollah that the group’s pagers came from a Hungary-based company that sourced them from Taiwan, because that sort of thing is perfectly normal. Most of the electronics Americans buy come from overseas, including our iPhones, whose parts come from dozens of countries before being pieced together primarily in China.

That’s a hard problem to fix. We can’t imagine Washington passing a law requiring iPhones to be made entirely in the United States. Labor costs are too high, and our country doesn’t have the domestic capacity to make these things. Our supply chains are deeply, inexorably international, and changing that would require bringing global economies back to the 1980s.

So what happens now? As for Hezbollah, its leaders and operatives will no longer be able to trust equipment connected to a network—very likely one of the primary goals of the attacks. And the world will have to wait to see if there are any long-term effects of this attack and how the group will respond.

But now that the line has been crossed, other countries will almost certainly start to consider this sort of tactic as within bounds. It could be deployed against a military during a war or against civilians in the run-up to a war. And developed countries like the United States will be especially vulnerable, simply because of the sheer number of vulnerable devices we have.

This essay originally appeared in The New York Times.

Introducing the new Code Club

Post Syndicated from Philip Colligan original https://www.raspberrypi.org/blog/introducing-the-new-code-club/

Today we’re unveiling a fresh look and feel for Code Club, along with a new ambition to inspire 10 million more young people to get creative with technology over the next decade.

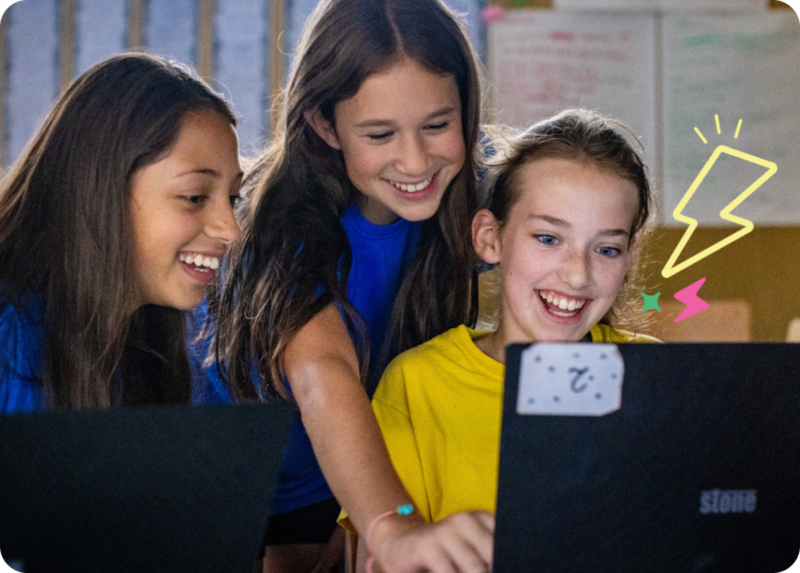
Three young tech creators at a laptop at a Code Club session.

Code Club is a network of free coding clubs where young people learn how to create with technology. Founded in the UK in 2012, it has grown to be a global movement that has already inspired more than 2 million young people to learn how to build their own apps, games, animations, websites, and so much more. 

We know that Code Club works. Independent evaluations have demonstrated that attending a Code Club helps young people develop their programming skills as well as wider life skills like confidence, resilience, and skills in problem-solving and communication. This impact is a result of the positive learning environment created by the teachers and volunteers that run Code Clubs, with young people enjoying the activities and developing skills independently and collaboratively — including young people who sometimes struggle in a formal classroom setting.

Just as important, we know that Code Clubs inspire young people from all backgrounds, including girls and young people from communities that are underrepresented in the technology sector. 

What’s changing and why 

While we are incredibly proud of the impact that Code Club has already achieved, we want to see many more young people benefiting, and that led us to set the ambitious goal to reach 10 million more young people over the next decade.

Two mentors and a young tech creator at a laptop at a Code Club session.

To help us figure out how to reach that ambition, we spent a lot of time this year listening to the community as well as engaging with parents, teachers, and young people who aren’t yet involved in Code Club. All of the changes we’ve made have been informed by those conversations and are designed to make it easier for educators and volunteers all over the world to set up and run Code Clubs.

The biggest change is that we are making Code Club a more flexible model that can be adapted to reflect your local context and culture to ensure that it is as meaningful as possible for the young people in your community. 

That means you can host a Code Club in a school or a community venue, like a library or makerspace; you can choose the age range and rhythm of meetings that make sense for your setting; and you can tailor the activities that you offer to the interests and skills of the young people you are serving. In order for the movement to be as inclusive as possible, you don’t even need to be called ‘Code Club’ to be an ‘Official Raspberry Pi Foundation Code Club’ and benefit from all the support we offer. 

Two mentors and a young tech creator at a computer at a Code Club session.

To support this change, we have developed a Code Club Charter that we ask all club leaders and mentors to sign up to. This sets out the principles that are shared by all Code Clubs, along with the commitments that the Raspberry Pi Foundation is making about our support to you.

We have launched a new website that makes it easier for you to find the information you need to set up and run your Code Club, along with an updated and simplified club leader guide. In a few weeks time, we are launching a new online course with guidance on how to run a successful club, and we will be adding to our programme of online community calls, webinars, and training to support a growing community of club leaders and mentors.

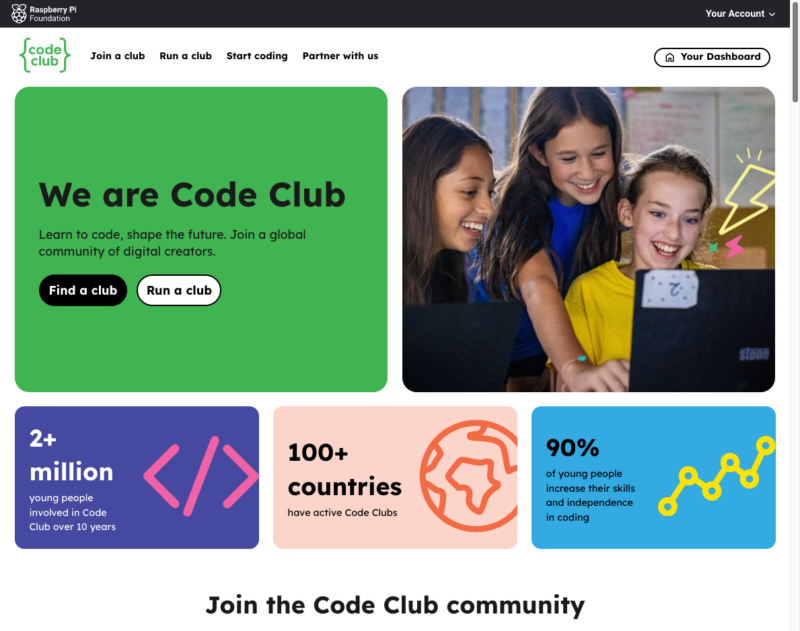
The Code Club website homepage.

One of the most important parts of our support for Code Clubs is the projects that help young people learn how to bring their ideas to life using a wide range of hardware and software. As they are created by experienced educators, based on research, rigorously tested, and translated into dozens of languages, you can have confidence that these projects lead to meaningful and lasting learning outcomes for the young people attending your club. Code Club projects enable young people to learn independently, meaning that mentors don’t need technical skills. 

What this means for CoderDojos 

Alongside Code Club, the Foundation supports CoderDojo, a network of coding clubs that started life in Cork, Ireland in 2011 and merged with the Raspberry Pi Foundation in 2017. 

In order to reduce duplication and make it easier for anyone to set up and run a coding club, we have decided to bring together the resources and support for all club leaders and mentors under one website, which is the new Code Club website.

There is no need for existing CoderDojos to change their name or anything about the way they operate. All registered CoderDojos will be able to manage their club in exactly the same way through the new website, and to access all of the support and resources that we offer to all coding clubs. New clubs will be able to register as CoderDojos.

Two young tech creators at a tablet at a Code Club session.

The ethos, experiences, and lessons from the CoderDojo community have been a vital part of the development of the new Code Club. We have worked hard to make sure that all existing CoderDojos feel that their values are reflected in the Charter, and that the guidance and resources we offer address their circumstances. 

CoderDojos will very much remain part of this community, and the Raspberry Pi Foundation will continue to celebrate and learn from the amazing work of CoderDojos all over the world. 

Code Club in the age of artificial intelligence 

With AI already transforming so many parts of our lives, it’s not surprising that some people are starting to ask whether young people even need to learn to code anymore. 

Three young tech creators at laptops at a Code Club session.

We’ve got a lot to say on this subject — so watch this space — but the short version is that learning how to create with technology has never been more important. The way that humans give instructions to computers is changing, and Code Club provides a way for young people to experiment with new technologies like AI in a safe environment. Over the next couple of weeks, we’ll be launching new Code Club projects that support young people to learn about AI technologies, including generative AI, and we’ll be providing support for club leaders and mentors on the topic too. 

Thank you and get involved

I want to end by saying a huge thank you to everyone who has been part of the Code Club journey so far, and particularly to everyone who has worked so hard on this project over the past year — far too many people to name here, but you know who you are. I also want to thank all of the parents, teachers, mentors, and partners who have provided the feedback and ideas that have shaped these changes.

A young tech creator at a tablet at a Code Club session.

Code Club and CoderDojo were both founded in the early 2010s by individuals who wanted to give more young people the opportunity to be digital creators, not just consumers. From that first Dojo in Cork, Ireland, and the first Code Clubs in London, UK, we’ve built a global movement that has empowered millions of young people to engage confidently with a world that is being transformed by digital technologies.

It’s never been a better time to get involved with Code Club, so please take a look and get in touch if you need any help or support to get started.

The post Introducing the new Code Club appeared first on Raspberry Pi Foundation.

GitHub Enterprise Cloud with data residency: How we built the next evolution of GitHub Enterprise using GitHub

Post Syndicated from Jim Wang original https://github.blog/engineering/engineering-principles/github-enterprise-cloud-with-data-residency/


Today, we announced that GitHub Enterprise Cloud will offer data residency, starting with the European Union (EU) on October 29, 2024, to address a critical desire from customers and enable an optimal, unified experience on GitHub for our customers.

Data residency and what it means for developers

We’ve heard for years from enterprises that being able to control where their data resides is critical for them. With data residency, organizations can now store their GitHub code and repository data in their preferred geographical region. With this need met, even more developers across the globe can build on the world’s AI-powered developer platform.

Enterprise Cloud with data residency provides enhanced user control and unique namespaces on ghe.com isolated from the open source cloud on github.com. It’s built on the security, business continuity, and disaster recovery capabilities of Microsoft Azure.

Image of a Contoso repository displaying a unique namespace which is magnified.

This is a huge milestone for our customers and for GitHub–a multi-year effort that required extensive time, effort, and dedication across the company. We’re excited to share a behind-the-scenes look at how we leveraged GitHub to develop the next evolution of Enterprise Cloud.

Designing the architecture for the next evolution of GitHub Enterprise

This effort started in summer of 2022 with a proof of concept (PoC) and involved teams across GitHub. We carefully considered which architecture would enable us to be successful. After iterating with different approaches, we decided to build the new offering as a feature set that extends Enterprise Cloud. This approach would allow us to be consistently in sync with features on github.com and provide the performance, reliability, and security that our customers expect. For hosting, we effectively leveraged Microsoft Azure’s scale, security, and regional footprint to produce a reliable and secured product with data residency built-in, without having to build new data centers ourselves.

As the home for all developers, developer experience is critically important for us. We recognized early on that consistency was important, so we sought to minimize differences in developing for Enterprise Cloud and Enterprise Cloud with data residency. To this end, the architecture across both is very similar, reducing complexity, risk, and development costs. The deployment model is familiar to our developers: it builds off of GitHub Actions. Also, changes to github.com and Enterprise Cloud with data residency are deployed minutes apart as part of a unified pipeline.

To accomplish this, we had to organize the work, modify our build and deployment systems, and validate the quality of the platform. We were able to do all three of these by using GitHub.

Organizing with GitHub Issues and Projects

To organize the project, we used GitHub Issues and Projects, taking advantage of multiple views to effectively drive work across multiple projects, more than 100 teams, and over 2,000 issues. Different stakeholders and teams could take advantage of these views to focus on the information most relevant to them. Our talented technical project management team helped coordinate updates and used the filtering and slicing capabilities of Projects to present continuously updated information for each milestone in an easily consumable way.

We also used upcoming features like issues hierarchy to help us understand relationships between issues, and issue types to help clearly classify issues across repositories. As part of using these features internally we were able to give feedback to the teams working on them and refine the final product. Keep an eye out for future announcements for issues hierarchy and issue types coming soon!

Image of hierarchies directly inside a GitHub project.

Image of issue types.

All of these powerful features helped us keep the initiative on track. We were able to clearly understand potential risk areas and partner across multiple teams to resolve blockers and complex dependencies, keeping the project effectively moving forward across multiple years.

Building Enterprise Cloud with data residency using GitHub

GitHub has always been built using GitHub. We wanted to continue this practice to set ourselves up for success with the new data residency feature. To this end, we continued leveraging GitHub Codespaces for development and GitHub Actions for continuous integration (CI). In addition, we added deployment targets for new regions. This produced a development, testing, and CI model that required no changes for our developers and a deployment process that was tightly integrated into the existing flow.

We have previously discussed our deploy then merge model, where we deploy branches before merging into the main branch. We expanded this approach to include successful deployments to Enterprise Cloud data residency targets before changes could be merged and considered complete, continuing to use the existing GitHub merge queue. A visualization of our monolithic deployment pipeline is shown in the figure below.

Image showing a visualization of the deployment pipeline.

We start by deploying to environments used by GitHub employees in parallel. This includes the internal environment for Enterprise Cloud with data residency discussed more in the next section. As we use GitHub every day to build GitHub, this step helps us catch issues as employees use the product before it impacts our customers. After automated and manual testing, we proceed to roll out to “Canary.” Canary is the name for the stage where we configure our load balancers to gradually direct an increasing percentage of github.com traffic to the updated version of the code in a staged manner. Additional testing occurs in between each stage. Once we successfully deploy the updated version of github.com to all users, we then deploy and validate Enterprise Cloud with data residency in the EU before finishing the process and merging the pull request.

Ensuring all deployments are successful before we merge means changes are deployed in sync across all Enterprise Cloud environments and monitored effectively. Note that in addition to deployments, we also use feature flags to gradually roll out changes to groups of customers to reduce risk. If a deployment to any target fails, we roll back the change completely. Once we have understood the failure and are ready to deploy again, the entire process starts from the beginning with the merge queue.

Finally, to maintain consistency across all teams and services, we created automation to generate deployment pipelines for over 100 services so, as new targets are introduced, each service automatically deploys to the new environment in a consistent order.

Using Enterprise Cloud with data residency ourselves

To create the best possible product, we also prioritized using it ourselves and stood up an isolated environment for this purpose. Using our GitHub migration tooling, we moved the day-to-day development for the team working on GitHub Enterprise Importer to that environment, and invested in updating our build, deploy, and development environments to support working from the data resident environment. Since its creation, we have deployed to this environment over 8,000 times. This gave us invaluable feedback about the experience of working in the product with issues, pull requests, and actions that we were able to address early in the development process. We were also able to iterate on our status page tooling and internal Service Level Objective (SLO) process with the new environment in mind. The team is continuing to work in this environment today and runs over 1,000 actions jobs a month. This is a testament to the stability and quality we’ve been able to deliver and our commitment to this feature.

What’s next

We are proud that we’ve been able to evolve Enterprise Cloud to offer data residency while using GitHub to organize, build, deploy, and test it. We’re excited to unlock GitHub for even more developers and for you to experience what we have built, starting on October 29, 2024 in the EU, with more regions on the way.

If you’re excited about Enterprise Cloud with data residency, please join us at GitHub Universe 2024 to learn more and hear from other companies how they’ve used this to accelerate software development and innovation.

The post GitHub Enterprise Cloud with data residency: How we built the next evolution of GitHub Enterprise using GitHub appeared first on The GitHub Blog.

Hy 1.0.0 released

Post Syndicated from jzb original https://lwn.net/Articles/991401/

Version 1.0.0 of Hy, a Lisp dialect that is embedded in Python, has been released
after nearly 12 years in development. This is the first stable release of the project:

Henceforth, breaking changes to documented parts of the language
(other than dropping support for versions of Python that are
themselves no longer supported by the CPython developers) will
increase the major version number, and my intention is for that not to
happen often, if at all.

The 1.0.0 release supports Python 3.8 through 3.13. See the documentation and the “Why Hy?” page for why
one might want to use it.

Jamba 1.5 family of models by AI21 Labs is now available in Amazon Bedrock

Post Syndicated from Antje Barth original https://aws.amazon.com/blogs/aws/jamba-1-5-family-of-models-by-ai21-labs-is-now-available-in-amazon-bedrock/

Today, we are announcing the availability of AI21 Labs’ powerful new Jamba 1.5 family of large language models (LLMs) in Amazon Bedrock. These models represent a significant advancement in long-context language capabilities, delivering speed, efficiency, and performance across a wide range of applications. The Jamba 1.5 family of models includes Jamba 1.5 Mini and Jamba 1.5 Large. Both models support a 256K token context window, structured JSON output, function calling, and are capable of digesting document objects.

AI21 Labs is a leader in building foundation models and artificial intelligence (AI) systems for the enterprise. Together, AI21 Labs and AWS are empowering customers across industries to build, deploy, and scale generative AI applications that solve real-world challenges and spark innovation through a strategic collaboration. With AI21 Labs’ advanced, production-ready models together with Amazon’s dedicated services and powerful infrastructure, customers can leverage LLMs in a secure environment to shape the future of how we process information, communicate, and learn.

What is Jamba 1.5?
Jamba 1.5 models leverage a unique hybrid architecture that combines the transformer model architecture with Structured State Space model (SSM) technology. This innovative approach allows Jamba 1.5 models to handle long context windows up to 256K tokens, while maintaining the high-performance characteristics of traditional transformer models. You can learn more about this hybrid SSM/transformer architecture in the Jamba: A Hybrid Transformer-Mamba Language Model whitepaper.

You can now use two new Jamba 1.5 models from AI21 in Amazon Bedrock:

  • Jamba 1.5 Large excels at complex reasoning tasks across all prompt lengths, making it ideal for applications that require high quality outputs on both long and short inputs.
  • Jamba 1.5 Mini is optimized for low-latency processing of long prompts, enabling fast analysis of lengthy documents and data.

Key strengths of the Jamba 1.5 models include:

  • Long context handling – With 256K token context length, Jamba 1.5 models can improve the quality of enterprise applications, such as lengthy document summarization and analysis, as well as agentic and RAG workflows.
  • Multilingual – Support for English, Spanish, French, Portuguese, Italian, Dutch, German, Arabic, and Hebrew.
  • Developer-friendly – Native support for structured JSON output, function calling, and capable of digesting document objects.
  • Speed and efficiency – AI21 measured the performance of Jamba 1.5 models and shared that the models demonstrate up to 2.5X faster inference on long contexts than other models of comparable sizes. For detailed performance results, visit the Jamba model family announcement on the AI21 website.

Get started with Jamba 1.5 models in Amazon Bedrock
To get started with the new Jamba 1.5 models, go to the Amazon Bedrock console, choose Model access on the bottom left pane, and request access to Jamba 1.5 Mini or Jamba 1.5 Large.

Amazon Bedrock - Model access to AI21 Jamba 1.5 models

To test the Jamba 1.5 models in the Amazon Bedrock console, choose the Text or Chat playground in the left menu pane. Then, choose Select model and select AI21 as the category and Jamba 1.5 Mini or Jamba 1.5 Large as the model.

Jamba 1.5 in the Amazon Bedrock text playground

By choosing View API request, you can get a code example of how to invoke the model using the AWS Command Line Interface (AWS CLI) with the current example prompt.

You can follow the code examples in the Amazon Bedrock documentation to access available models using AWS SDKs and to build your applications using various programming languages.

The following Python code example shows how to send a text message to Jamba 1.5 models using the Amazon Bedrock Converse API for text generation.

import boto3
from botocore.exceptions import ClientError

# Create a Bedrock Runtime client.
bedrock_runtime = boto3.client("bedrock-runtime", region_name="us-east-1")

# Set the model ID.
# modelId = "ai21.jamba-1-5-mini-v1:0"
model_id = "ai21.jamba-1-5-large-v1:0"

# Start a conversation with the user message.
user_message = "What are 3 fun facts about mambas?"
conversation = [
    {
        "role": "user",
        "content": [{"text": user_message}],
    }
]

try:
    # Send the message to the model, using a basic inference configuration.
    response = bedrock_runtime.converse(
        modelId=model_id,
        messages=conversation,
        inferenceConfig={"maxTokens": 256, "temperature": 0.7, "topP": 0.8},
    )

    # Extract and print the response text.
    response_text = response["output"]["message"]["content"][0]["text"]
    print(response_text)

except (ClientError, Exception) as e:
    print(f"ERROR: Can't invoke '{model_id}'. Reason: {e}")
    exit(1)

The Jamba 1.5 models are perfect for use cases like paired document analysis, compliance analysis, and question answering for long documents. They can easily compare information across multiple sources, check if passages meet specific guidelines, and handle very long or complex documents. You can find example code in the AI21-on-AWS GitHub repo. To learn more about how to prompt Jamba models effectively, check out AI21’s documentation.

Now available
AI21 Labs’ Jamba 1.5 family of models is generally available today in Amazon Bedrock in the US East (N. Virginia) AWS Region. Check the full Region list for future updates. To learn more, check out the AI21 Labs in Amazon Bedrock product page and pricing page.

Give Jamba 1.5 models a try in the Amazon Bedrock console today and send feedback to AWS re:Post for Amazon Bedrock or through your usual AWS Support contacts.

Visit our community.aws site to find deep-dive technical content and to discover how our Builder communities are using Amazon Bedrock in their solutions.

— Antje

AWS Weekly Roundup: Amazon EC2 X8g Instances, Amazon Q generative SQL for Amazon Redshift, AWS SDK for Swift, and more (Sep 23, 2024)

Post Syndicated from Abhishek Gupta original https://aws.amazon.com/blogs/aws/aws-weekly-roundup-amazon-ec2-x8g-instances-amazon-q-generative-sql-for-amazon-redshift-aws-sdk-for-swift-and-more-sep-23-2024/

AWS Community Days have been in full swing around the world. I am going to put the spotlight on AWS Community Day Argentina where Jeff Barr delivered the keynote, talks and shared his nuggets of wisdom with the community, including a fun story of how he once followed Bill Gates to a McDonald’s!

I encourage you to read about his experience.

Last week’s launches
Here are the launches that got my attention, starting off with the GA releases.

Amazon EC2 X8g Instances are now generally available – X8g instances are powered by AWS Graviton4 processors and deliver up to 60% better performance than AWS Graviton2-based Amazon EC2 X2gd instances. These instances offer larger sizes with up to 3x more vCPU (up to 48xlarge) and memory (up to 3TiB) than Graviton2-based X2gd instances.

Amazon Q generative SQL for Amazon Redshift is now generally available – Amazon Q generative SQL in Amazon Redshift Query Editor is an out-of-the-box web-based SQL editor for Amazon Redshift. It uses generative AI to analyze user intent, query patterns, and schema metadata to identify common SQL query patterns directly within Amazon Redshift, accelerating the query authoring process for users and reducing the time required to derive actionable data insights.

AWS SDK for Swift is now generally available – AWS SDK for Swift provides a modern, user-friendly, and native Swift interface for accessing Amazon Web Services from Apple platforms, AWS Lambda, and Linux-based Swift on Server applications. Now that it’s GA, customers can use AWS SDK for Swift for production workloads. Learn more in the AWS SDK for Swift Developer Guide.

AWS Amplify now supports long-running tasks with asynchronous server-side function calls – Developers can use AWS Amplify to invoke Lambda function asynchronously for operations like generative AI model inferences, batch processing jobs, or message queuing without blocking the GraphQL API response. This improves responsiveness and scalability, especially for scenarios where immediate responses are not required or where long-running tasks need to be offloaded.

Amazon Keyspaces (for Apache Cassandra) now supports add-column for multi-Region tables – With this launch, you can modify the schema of your existing multi-Region tables in Amazon Keyspaces (for Apache Cassandra) to add new columns. You only have to modify the schema in one of its replica Regions and Keyspaces will replicate the new schema to the other Regions where the table exists.

Amazon Corretto 23 is now generally available – Amazon Corretto is a no-cost, multi-platform, production-ready distribution of OpenJDK. Corretto 23 is an OpenJDK 23 Feature Release that includes an updated Vector API, expanded pattern matching and switch expression, and more. It will be supported through April, 2025.

Use OR1 instances for existing Amazon OpenSearch Service domains – With OpenSearch 2.15, you can leverage OR1 instances for your existing Amazon OpenSearch Service domains by simply updating your existing domain configuration, and choosing OR1 instances for data nodes. This will seamlessly move domains running OpenSearch 2.15 to OR1 instances using a blue/green deployment.

Amazon S3 Express One Zone now supports AWS KMS with customer managed keys – By default, S3 Express One Zone encrypts all objects with server-side encryption using S3 managed keys (SSE-S3). With S3 Express One Zone support for customer managed keys, you have more options to encrypt and manage the security of your data. S3 Bucket Keys are always enabled when you use SSE-KMS with S3 Express One Zone, at no additional cost.

Use AWS Chatbot to interact with Amazon Bedrock agents from Microsoft Teams and Slack – Before, customers had to develop custom chat applications in Microsoft Teams or Slack and integrate it with Amazon Bedrock agents. Now they can invoke their Amazon Bedrock agents from chat channels by connecting the agent alias with an AWS Chatbot channel configuration.

AWS CodeBuild support for managed GitLab runners – Customers can configure their AWS CodeBuild projects to receive GitLab CI/CD job events and run them on ephemeral hosts. This feature allows GitLab jobs to integrate natively with AWS, providing security and convenience through features such as IAM, AWS Secrets Manager, AWS CloudTrail, and Amazon VPC.

We launched existing services in additional Regions:

Other AWS news
Here are some additional projects, blog posts, and news items that you might find interesting:

Secure Cross-Cluster Communication in EKS – It demonstrates how you can use Amazon VPC Lattice and Pod Identity to secure cross-EKS-cluster application communication, along with an example that you can use as a reference to adapt to your own microservices applications.

Improve RAG performance using Cohere Rerank – This post focuses on improving search efficiency and accuracy in RAG systems using Cohere Rerank.

AWS open source news and updates – My colleague Ricardo Sueiras writes about open source projects, tools, and events from the AWS Community; check out Ricardo’s page for the latest updates.

Upcoming AWS events
Check your calendars and sign up for upcoming AWS events:

AWS Community Days – Join community-led conferences that feature technical discussions, workshops, and hands-on labs led by expert AWS users and industry leaders from around the world. Upcoming AWS Community Days are in Italy (Sep. 27), Taiwan (Sep. 28), Saudi Arabia (Sep. 28)), Netherlands (Oct. 3), and Romania (Oct. 5).

Browse all upcoming AWS led in-person and virtual events and developer-focused events.

That’s all for this week. Check back next Monday for another Weekly Roundup!

— Abhishek

This post is part of our Weekly Roundup series. Check back each week for a quick roundup of interesting news and announcements from AWS!

[$] Resources for learning Rust for kernel development

Post Syndicated from daroc original https://lwn.net/Articles/990619/

Dirk Behme led a second session, back-to-back with
his session on error handling at
Kangrejos 2024, discussing providing better guidance for users of the kernel’s
Rust abstractions. Just after that,
Carlos Bilbao and Miguel Ojeda had their own time slot dedicated to collecting
resources that could be of use to someone trying to come up to speed
on kernel development in
Rust. The attendees provided a lot of guidance in both sessions, and
discussed what they could do to make things easier for people coming
from non-Rust backgrounds.

Hacking the “Bike Angels” System for Moving Bikeshares

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2024/09/hacking-the-bike-angels-system-for-moving-bikeshares.html

I always like a good hack. And this story delivers. Basically, the New York City bikeshare program has a system to reward people who move bicycles from full stations to empty ones. By deliberately moving bikes to create artificial problems, and exploiting exactly how the system calculates rewards, some people are making a lot of money.

At 10 a.m. on a Tuesday last month, seven Bike Angels descended on the docking station at Broadway and 53rd Street, across from the Ed Sullivan Theater. Each rider used his own special blue key -­- a reward from Citi Bike—­ to unlock a bike. He rode it one block east, to Seventh Avenue. He docked, ran back to Broadway, unlocked another bike and made the trip again.

By 10:14, the crew had created an algorithmically perfect situation: One station 100 percent full, a short block from another station 100 percent empty. The timing was crucial, because every 15 minutes, Lyft’s algorithm resets, assigning new point values to every bike move.

The clock struck 10:15. The algorithm, mistaking this manufactured setup for a true emergency, offered the maximum incentive: $4.80 for every bike returned to the Ed Sullivan Theater. The men switched direction, running east and pedaling west.

Nicely done, people.

Now it’s Lyft’s turn to modify its system to prevent this hack. Thinking aloud, it could try to detect this sort of behavior in the Bike Angels data—and then ban people who are deliberately trying to game the system. The detection doesn’t have to be perfect, just good enough to catch bad actors most of the time. The detection needs to be tuned to minimize false positives, but that feels straightforward.

The collective thoughts of the interwebz