The conversation around AI security is full of anxiety. Every week, new headlines warn of jailbreaks, prompt injection, agents gone rogue, and the rise of LLM-enabled cybercrime. It’s easy to come away with the impression that AI is fundamentally uncontrollable and dangerous, and therefore something we need to lock down before it gets out of hand.
But as a security practitioner, I wasn’t convinced. Most of these warnings are based on hypothetical examples or carefully engineered demos. They raise important questions, but rarely answer the most basic one: What does the real attack surface of today’s AI systems actually look like?
So instead of offering another opinion, I ran the numbers.
The method: Focused, real-world measurement
To ground the conversation in reality, I focused on MCP, the Model Context Protocol. This framework is widely used to help language models interact with tools, APIs, and external systems. It’s open source, replicated across many environments, and built for practical integration. That makes it an ideal test case for understanding actual exposure.
No adversarial prompting. No artificial exploits. Just a measurement of what real MCP servers expose. We used SDK import analysis to locate active repositories, filtered out those that wouldn’t run, and examined the tool schemas to understand what each was capable of.
What the data tells us
The MCP servers that met our criteria showed a familiar pattern. They exposed well-understood primitives used throughout modern software systems.
Observed capability classes:
Filesystem access
HTTP requests
Database queries
Local script or process execution
Orchestration and tool chaining
Read-only API search
These are not exotic capabilities unique to AI. They’re already embedded in cloud automation, infrastructure-as-code, and modern DevOps stacks. MCP simply gives them structure.
The frequency of high-severity risk is low
One of the most unexpected findings was the rarity of arbitrary code execution. Despite warnings in the media, this turned out to be the least common capability among all operational MCP servers analyzed.
This matters. It suggests that real-world deployments of AI tooling are not as reckless as some narratives claim. The most common issues are the ones we’ve known for years: weak defaults, excessive permissions, and poor input handling. There’s no mystery there (and that’s encouraging).
Where the real risk builds: Composition
The problem arises when those primitives are combined. Individually, most of the MCP servers we studied were low risk. But when orchestration enters the picture, the attack surface expands.
Some real-world examples we observed:
HTTP fetch + filesystem write = persistence or content injection
These combinations reflect what adversaries already do in non-AI environments. MCP just reduces friction in putting the pieces together.
A critical counterpoint: The ‘best effort’ reality
The focus on constraining the model via schema and architecture is essential for ‘secure by design,’ yet a critical counterpoint must be considered as the industry evolves: We may not be able to stop many insecure AI applications (e.g., those built on architectures like OpenClaw or Claude Code) from shipping with insecure design choices. Similarly, the insecure design path for AI could force security teams to rely on non-deterministic, ‘best effort’ prompt injection defenses to prevent data exfiltration and remote code execution, rather than influencing developers toward inherently secure application design.
While the secure boundary is the schema, and we must influence application developers to adopt secure-by-design principles, the future suggests there will be many cases where this influence fails. This means security leaders must also prepare for a hybrid reality of championing architectural security while also building and operating robust, best effort runtime defenses to manage the fallout from the inevitable wave of insecure AI applications.
A shift in where security happens
As we embed AI deeper into operational systems, the control points change. Historically, we validated inputs at the UI layer, enforced roles through IAM, and wrapped logic in application code.
With AI agents, those controls now live in:
The orchestration layer
Tool composition workflows
Schema contracts
Execution sandboxes
Security needs to follow the shift. That means auditing tool chains, setting strict schema policies, isolating execution contexts, and applying existing practices like least privilege and defense in depth to this new architecture.
What security teams should do now
Security and architecture leaders can start applying pressure in the right places today:
Map AI tooling to known primitives Don’t treat these systems as unknowns. Most expose capabilities like file handling, HTTP fetches, or basic shell commands – all of which are familiar territory for teams leveraging threat intelligence effectively.
Assess schema design before worrying about prompts The schema defines what tools the AI can call and how. Poorly scoped parameters, such as unbounded URLs or file paths, are far more dangerous than clever prompts.
Limit orchestration where possible Composability increases risk. If orchestration is required, monitor it like critical automation infrastructure.
Audit your environment for capability sprawl Look for AI-connected services that may expose multiple sensitive capabilities together. Risk scales when these tools are combined.
Apply existing enterprise controls Network segmentation, credential scoping, logging, and behavioral detections still work. Least privilege access is especially relevant in AI-integrated environments where tool chaining can escalate access unintentionally. AI requires adaptation, not reinvention.
Understanding the risk of AI without the hype
This blog condenses findings from my recent research, where I set out to answer a straightforward question: what are AI systems actually exposing in the real world today? Instead of relying on hypotheticals or fear-driven narratives, I looked at real, runnable Model Context Protocol (MCP) servers and measured their exposed capabilities and architectural design.
If you’re looking for the technical deep dive, including methodology, data sets, and schema-level breakdowns, you can read the original research published on HackerNoon. You can also explore more of our ongoing threat analysis and security research on the Rapid7 Research Hub.
The bottom line: AI introduces complexity and scale, but the fundamental security principles remain the same. The real challenge is whether security teams can adapt traditional controls to new environments and influence developers toward inherently secure application design, rather than being forced to rely on non-deterministic, ‘best effort’ defenses like prompt injection mitigation.
When was the last time you had a serious conversation about cybersecurity that didn’t touch on ransomware?
We all know that it’s one of the most persistent and damaging threats out there. Yet, this isn’t because it’s new—ransomware’s been around since 1989—but because we are making it far too easy for threat actors.
This year at RSA Conference, I gave a talk on why ransomware is still a thing in the year 2025. I explored key challenges, the rapid attack evolution, how the industry has responded, and whether today’s ransomware actors are truly innovating or just recycling old tricks.
Ransomware remains a crisis because we are still giving attackers the upper hand. To regain control, we need to understand how we’ve made it so easy for them, and what we can do to change that.
How did we get here? And why haven’t we stopped ransomware yet?
Cybersecurity investments continue to climb, with worldwide end-user spending on information security projected to reach $212 billion in 2025, according to Gartner. Still, the costs of cybercrime are continuing to escalate. With the FBI reporting a record $16.6 billion in losses in 2024 and identifying 67 new ransomware variants, it’s clear the threat landscape continues to thrive.
How is still this happening? With the steady increase in global law enforcement and legislative initiatives, as well as advancements in offensive and defensive technologies, shouldn’t progress be happening?
The fact is, attacks are escalating just as quickly. As defenders look to shift left, so do attackers who are probing earlier and adapting faster.
For example, stronger endpoint protection pushed attackers to target the network edge, exploiting vulnerabilities in firewalls, VPNs, file transfer solutions, and cloud infrastructure. The shift to multi-factor authentication (MFA) adoption was countered by attackers adjusting their social engineering to create MFA fatigue attacks. As early AI-powered threat detection improved security, ransomware groups adjusted their tactics to better blend into normal network traffic.
The economics of ransomware
Continued successes have enabled the underground cybercriminal economy to flourish and invest in even better tools and tactics. The more mature groups now run structured, professional operations that are reinvesting ransom payments into new exploits, tools, and personnel.
Successful groups like RansomHub are estimated to be pulling in more than $40m, with profits at around $12m after expenses and splitting with affiliates.
Leaked chat logs from ransomware groups such as Black Basta and Conti reveal that they often function like legitimate tech start-ups, complete with affiliate programs, customer support teams, and even bonuses for their top-performing operatives.
With six-figure sums being spent on exploits—leaked Black Basta chat logs confirmed the offer of an Ivanti zero-day for $200,000—attackers can acquire new tools faster than security teams can patch vulnerabilities. This constant reinvestment fuels an escalating cycle of attacks.
Established gangs are branching out into RaaS as a reliable money spinner, allowing lesser groups to launch attacks above their paygrade.
The more organizations are tempted by the ‘easy’ way out by paying up, the more capital threat groups have at their disposal. Big payouts also encourage gangs to hike up their ransom demands further. Meanwhile, paying is no guarantee of regaining stolen data—and attackers may return to exploit previous victims all over again.
But are ransomware groups truly innovating… or just lazy?
One of the biggest fears around ransomware gangs is the prospect of them bringing out advanced and unknown new attack tactics.
We certainly do see some top-tier gangs investing in cutting-edge techniques. These include branching out into new programming languages such as Rust, Go, and Nim to evade traditional detection methods and developing stronger encryption techniques to make data recovery more difficult.
Meanwhile, some groups are exploring firmware-based ransomware, embedding malware in UEFI/BIOS to evade detection. Conti chat logs confirm active research into these techniques. If adopted widely, these threats could eventually take ransomware to a new level.
While AI is a leading concern, it isn’t widespread in ransomware yet. Chiefly because the old methods are still working for the threat groups. However, attackers are using AI for social engineering, including phishing chatbots and deepfake scams.
So, certainly there is innovation in the field, at least at the top end. But when you start looking at the trends, it’s apparent that groups are usually doing just enough to stay ahead of their victims and aren’t typically experimenting the way the forefront of the legitimate tech sector does.
There are a lot of fields we aren’t really seeing them explore. For example, I’ve considered the potential around targeting chipsets in an attack. If you put some malicious code into the firmware controlling your operating system, I can load ransomware in the CPU and execute the ransomware from the chipset. There’s really no way for an antivirus tool to spot that before it activates during boot up. We’ll leave that there though for now—we don’t want to give them ideas…
Anyway, the fact is most threat groups prioritize efficiency over true innovation, and there are clear signs of groups cutting corners wherever possible. Groups such as LockBit and Conti have borrowed from REvil’s leaked source code instead of writing their own, for example. As the old saying goes, “if it ain’t broke…”
While groups have become more automated, they typically scale up existing operations rather than investing in new malware and tactics. Further, simple phishing attacks continue to do the trick in most cases. Why bother with advanced exploits and AI-powered campaigns if your target still isn’t using MFA?
Fighting ransomware starts with the fundamentals
A dozen years after attacks like CryptoLocker set the trend for modern ransomware, it remains a critical threat as attackers continue exploiting the same gaps repeatedly. Weak credentials, unpatched vulnerabilities, and poor incident response planning are all maintaining ransomware’s status as a reliable moneymaker.
Enterprises must get their fundamentals right to break the cycle of attacks.
Many firms still lack full visibility into their attack surface, for example. Security teams cannot effectively defend their organizations without comprehensive visibility of their systems and the ability to identify where to implement controls that prevent unauthorized access, privilege escalation, and lateral movement.
MFA, while highly effective, is often deployed and configured incorrectly and does not cover critical systems, especially edge technologies like SSL VPNs, firewalls, and cloud services.
Likewise, vulnerability patching is another critical area that is often not completed quickly or thoroughly enough, creating a wide window for attackers to use exploits before fixes are applied.
At first, addressing the prioritization issue can seem daunting. Out of the hundreds of vulnerabilities a business may face, where do they start? In these situations context is key, so a good place to start is by bringing together technologies and curated intelligence, which provide the necessary context to prioritize patching. If organizations can boost awareness of actively exploited vulnerabilities, and patch these proactively, then the overall risk they face will be lowered.
Beyond prevention, organizations need to test their response capabilities. Red team and tabletop exercises are essential to testing how well teams can detect, contain, and recover from an attack. Firms must develop response and data recovery strategies that do not rely on paying ransoms, removing the financial incentive behind groups carrying out attacks.
While a lot of companies have this down on paper, they may not have gone into enough depth for the real thing. What if an attack strikes and the main decision-maker is on vacation and they didn’t bring their cell to the beach? Who’s the replacement, what happens next? All these things need to be planned out and tested in detail.
So yes, ransomware is still a problem in 2025, and it will remain central to security discussions. However, the sophistication of this threat is not as daunting as it may seem. Threat actors are opportunists who cut corners and rely more on defenders making mistakes than their own skillsets.
To start winning this battle, organizations don’t need to take drastic measures. They need to get the basics right and take back control. No more giving the adversary easy wins.
The ransomware landscape in 2024 continued to evolve at a rapid pace, outgrowing many of the trends we saw in 2023. Threat actors remained relentless and innovative, targeting organizations of all sizes and sectors. In this post, we’ll examine the latest data points, discuss notable groups, and estimate the potential impact on victims — helping security teams plan their defenses for the months ahead.
2024 by the Numbers
Mid last year, Rapid7 Labs released our Ransomware Radar Report highlighting key stats for the first half of 2024. Here is how 2024 played out as a whole:
Total number of leak site posts: 5,939
Number of active ransomware groups: 75
Average number of active groups per month: 45
Average ransom payment in Q3 2024: $479,237 (Source: Coveware)
Median ransom payment in Q3 2024: $200,000 (Source: Coveware)
Median percentage of companies that pay: 32% (Source: Coveware)
These numbers offer insight into just how expansive ransomware activity has become. While the overall figures are alarming, it’s the variety of actors and their ability to adapt that pose the greatest challenge for defenders.
Top 10 Ransomware Groups
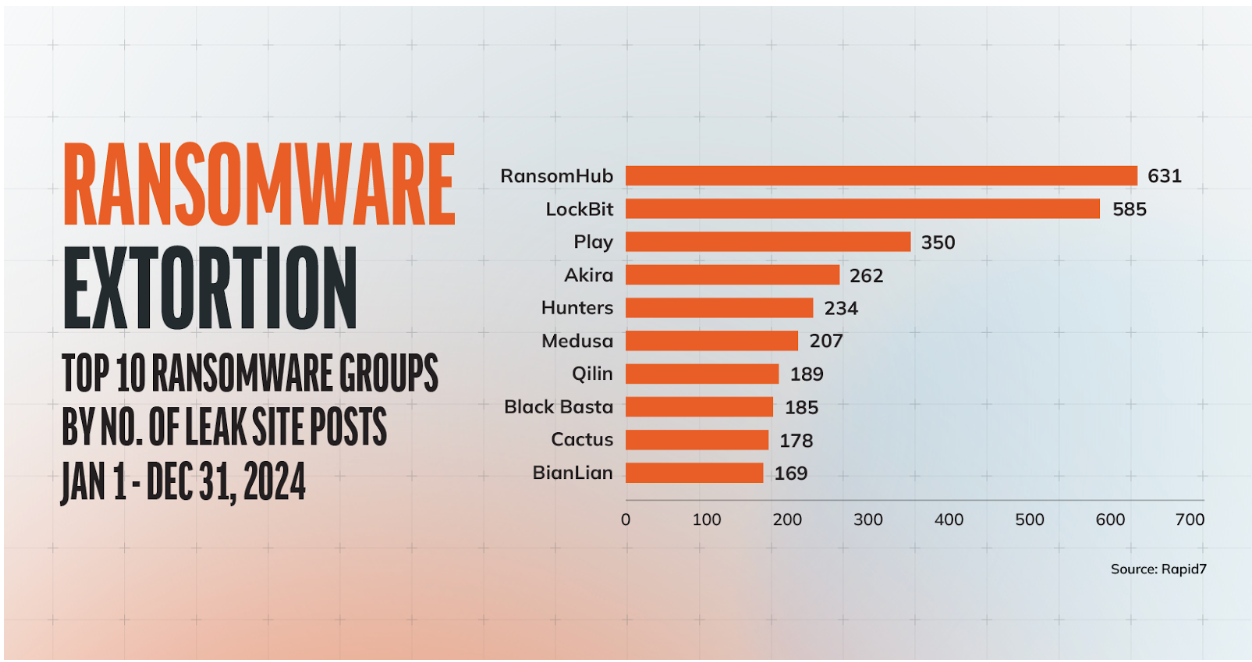
Below are the 10 most prolific ransomware groups in 2024, ranked by the number of posts on leak sites:
While these numbers reflect public disclosures, many victims choose to negotiate privately, meaning the true scope could be significantly higher.
The Cl0p group recently disclosed exploiting a vulnerability in Cleo file transfer software, further illustrating how threat actors pivot between high-profile platform vulnerabilities with minimal downtime. While the group avoids using conventional ransomware payloads, they still rely on a leak site to extort payment from victims. Because Cl0p’s business model isn’t driven by fully encrypting victims’ data, the ransom amounts they demand — and ultimately receive — remain opaque, making it difficult to quantify their financial impact within the broader ransomware ecosystem.
Estimated Financial Impact
Based on the median payment amount of $200,000 cited above and the stat that about 32% of companies choose to pay, we can make **rough** estimates of total potential revenue generated by these groups.
Note that this calculation assumes:
Each post represents one victim.
32% of those victims pay.
Ransom is always $200,000.
These assumptions likely understate the actual impact, as some victims pay more (the average is $479,237). Even so, the total in 2024 could easily exceed $380 million in ransom paid.
Group
Posts
32% of Posts (Paying Victims)
Hypothetical Revenue (USD)
RansomHub
631
201.92
$40,384,000
LockBit
585
187.20
$37,440,000
Play
350
112
$22,400,000
Akira
262
83.84
$16,768,000
Hunters
234
74.88
$14,976,000
Medusa
207
66.24
$13,248,000
Qilin
189
60.48
$12,096,000
Black Basta
185
59.20
$11,840,000
Cactus
178
56.96
$11,392,000
BianLian
169
54.08
$10,816,000
Table Note: These calculations are illustrative only; actual outcomes will differ.
Trends and Observations
Following are four trends we’re seeing in Rapid7 Labs, based on the global threat intelligence we gather as well as input from our internal research and open source communities.
1. Proliferation of Groups: With over 75 active groups, it’s clear that the barrier to entry for launching ransomware campaigns remains relatively low. In addition, fragmented groups are splintering and rebranding, making it more difficult to track and mitigate.
2. Persistent Dominance: Teams like RansomHub, Akira, and Fog continue to reign at the top, demonstrating sophisticated extortion strategies and steady affiliate growth.
3. Increased Transparency on the Victim Side: More organizations are disclosing breaches to comply with emerging regulations as well as to maintain customer trust. These self-reports, combined with the data ransomware actors post as a form of extortion, can give us a view of the threat. Still, not all attacks become public, obfuscating the true scale of the ransomware problem.
4. Rise of Double and Triple Extortion: Threat actors often demand multiple payments for data release, encryption keys, and in some cases, to prevent DDoS attacks or direct contact with partners and clients.
An additional observation: LockBit remained active throughout 2024, even as it became the focus of significant law enforcement attention. In a recent case, a dual Russian-Israeli national was charged for allegedly serving as a LockBit developer — an accusation that centers on crafting malicious code, overseeing affiliate activities, and orchestrating ransomware attacks worldwide. The indictments underscore intensified global cooperation, with agencies from the United States and the United Kingdom coordinating to disrupt LockBit’s infrastructure and hold key figures accountable. While LockBit continues to operate, these collective enforcement actions have highlighted the value of cross-border partnerships in mitigating ransomware threats
Building Resilience
Now that we’ve looked at some numbers and trends, let’s examine how we can use these learnings to inform decision-making and enable conversations at the executive level:
– Prepare for Multiple Vectors: Ransomware attacks often begin with credential compromise, phishing campaigns, or exploitation of unpatched vulnerabilities. Build layered security defenses accordingly.
– Secure Collaborations: Ensure robust security protocols with third parties, given the reliance on supply chains and outsourced IT services.
– Incident Response Readiness: Create clear IR plans that include legal and public relations strategies. In addition, we highly recommend that companies hold twice-annual tabletop exercises to test the efficacy of their ransomware IR plans. Rapid containment and a well-managed response can help minimize financial and reputational damage.
– Ongoing Risk Assessment: Regularly revisit threat models, especially as top-tier groups (like RansomHub or Cl0p) adopt new tactics and expand their affiliate networks.
Planning Ahead
Looking at the big picture, the financial incentives for cybercriminals are undeniable. Even if only one-third of victims pay a median of $200,000, the potential revenue surpasses $380 million — and that’s likely just the tip of the iceberg. This underscores three critical points for defenders:
1. Defense in Depth: Organizations must invest in proactive measures, from user awareness training and robust patching to strict access control and secure backups.
2. Threat Intelligence: Regularly monitor emerging ransomware groups and tactics to tailor defenses. Knowing who is targeting your industry and their methods is essential.
3. Commanding Your Attack Surface:
In line with Rapid7’s emphasis on complete visibility and proactive security, it’s essential that organizations maintain a continuous view of their external footprint. This includes:
– Regular Scanning: With automated tools that identify internet-facing assets and highlight newly exposed services or vulnerabilities.
– Real-time Monitoring: For detecting changes in cloud environments, development pipelines, and system deployments.
– Holistic Patch Management: To prioritize fixes based on known exploits and potential impact to reduce windows of opportunity for attackers.
By commanding your attack surface, you can reduce the likelihood of unpatched systems and publicly exposed services becoming easy entry points for ransomware groups.
Conclusion
The 2024 ransomware landscape signals an ongoing escalation in the volume, variety, and financial impact of attacks. Groups like RansomHub, Akira, and Cl0p demonstrate how quickly affiliates can scale, while many new entrants take advantage of commoditized ransomware-as-a-service models. For organizations of all sizes, building resilience, staying informed, and preparing a strong response plan are critical steps in countering this persistent and evolving threat.
Disclaimer: The statistics and financial estimates shared in this blog are based on public data and should be considered general indicators rather than exact figures. Real-world incidents often involve factors that deviate from these simplified calculations.
Many thanks to Rapid7 MDR and incident response teams for their contributions to this analysis.
While investigating incidents related to Cleo software exploitation, Rapid7 Labs and MDR observed a novel, multi-stage attack that deploys an encoded Java Archive (JAR) payload. Our investigation revealed that the JAR file was part of a modular, Java-based Remote Access Trojan (RAT) system. This RAT facilitated system reconnaissance, file exfiltration, command execution, and encrypted communication with the attacker’s command-and-control (C2) server. Its modular architecture includes components for dynamic decryption, network management, and staged data transfer.
It’s worthwhile to note that this isn’t necessarily the only payload that has or will be deployed in attacks targeting Cleo software — it’s entirely possible an alternate payload could be leveraged. This underscores the importance of timely detection and response capabilities, as well as the critical role of monitoring assets that may be impacted by unknown zero-day threats.
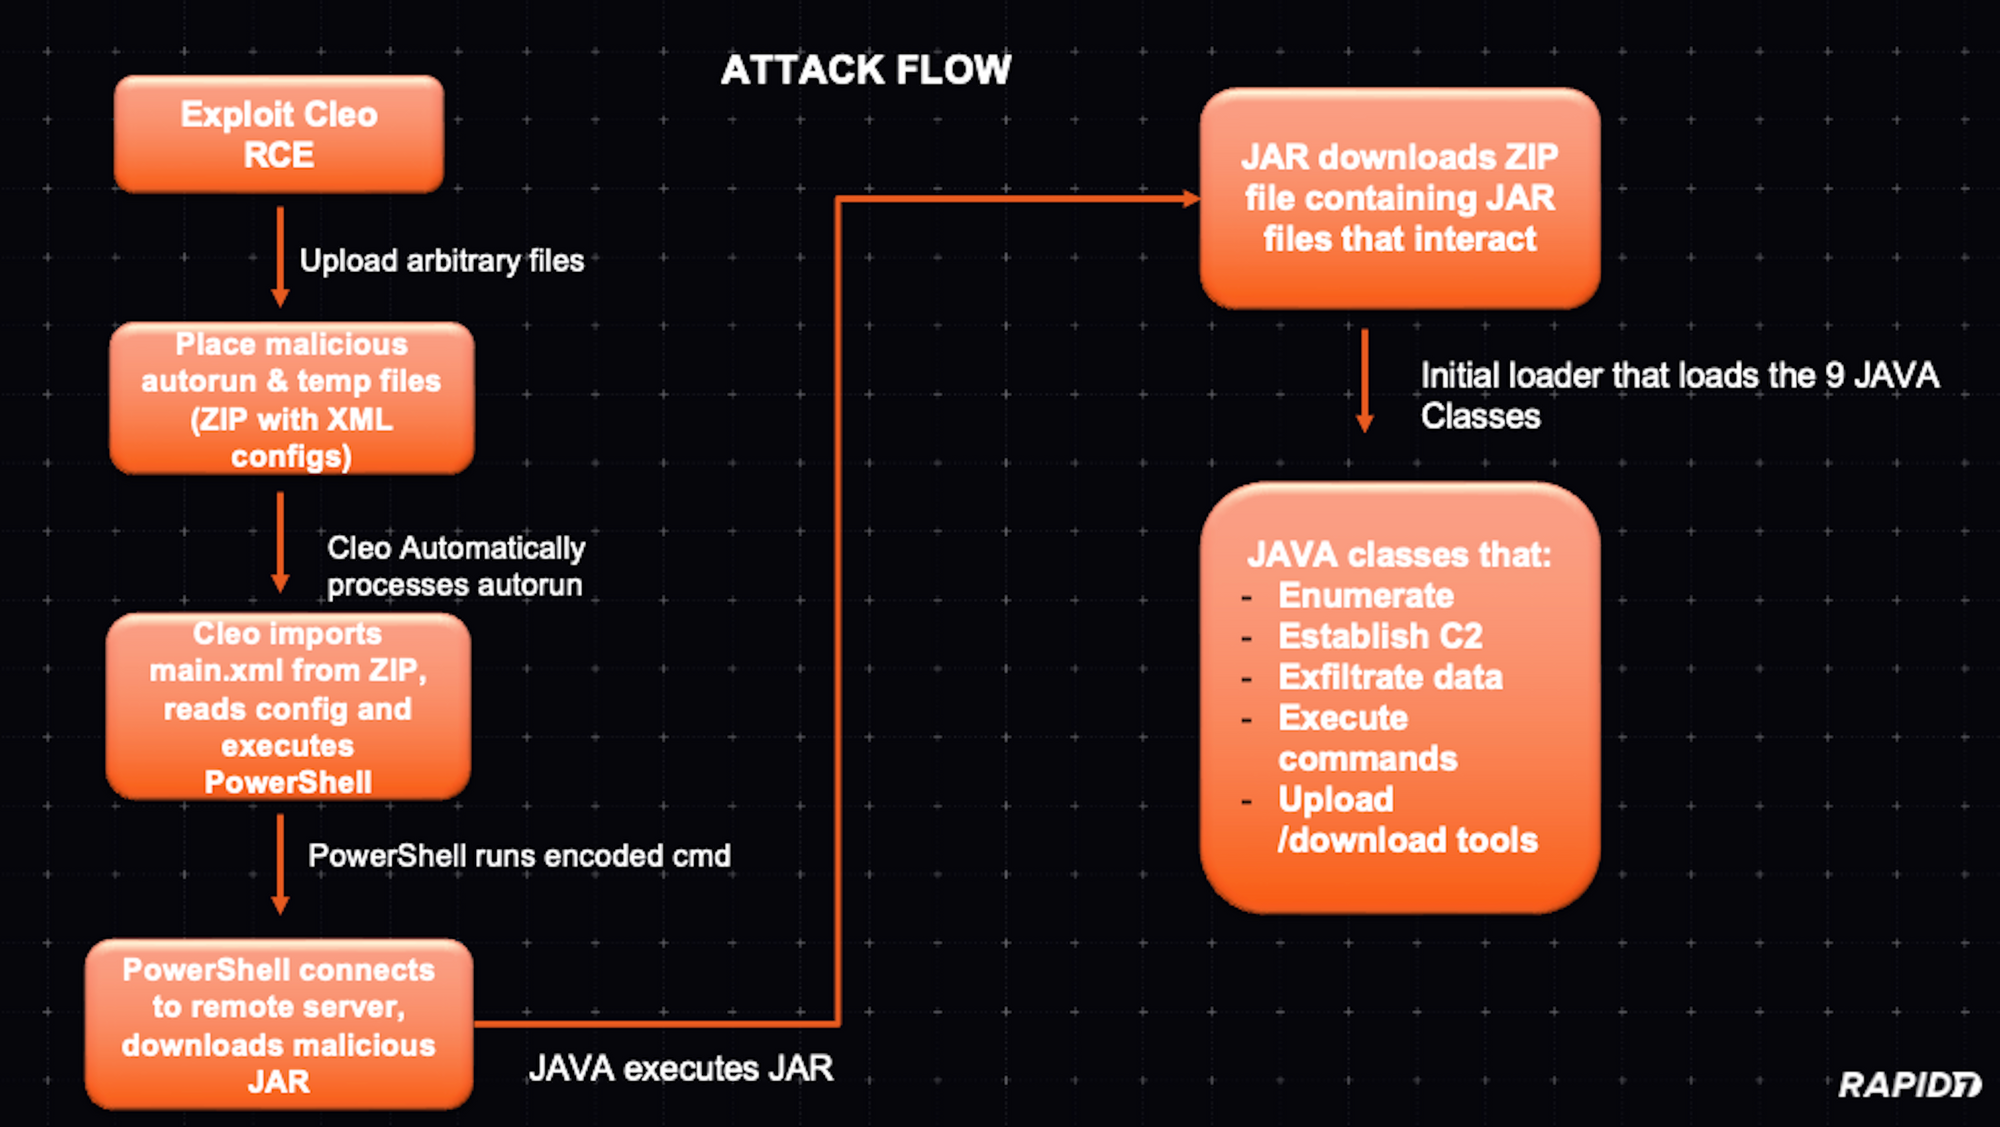
At a high level, the attack flow can be visualized like so:
As Huntress pointed out in their blog on this threat campaign, part of the attack chain involves uploading and executing an XML file as part of a ZIP. When analyzing the XML file that contains the PowerShell code, we looked at the code to understand how the code would trigger in line with the known CVE (CVE-2024-50623) and the new CVE (still pending) for the unauthenticated malicious hosts vulnerability in Cleo software.
The XML snippet appears to define a “Host” and “Mailbox” configuration in Cleo Integration Suite (e.g., Harmony, VLTrader, or LexiCom). Cleo software often uses XML-based configuration files for trading partner setups, hosts, mailboxes, and scheduled actions or commands. Each <Host> element represents a communication endpoint, and each <Mailbox> often represents a sub-endpoint or logical folder.
The <Action> elements define which tasks (commands, scripts, or transfers) should be performed. Looking at the code of our XML, we observed a suspicious element.
Under <Mailbox> there is an <Action> element with actiontype=”Commands”. Inside this action, there’s a <Commands> tag that runs:
SYSTEM cmd.exe /c "powershell -NonInteractive -EncodedCommand <base64_data>" > webserver/temp/webserver-<GUID>.swp
The <Commands> directive is invoking cmd.exe which runs PowerShell with an encoded command. The command is outputting to a .swp file, possibly to hide or store results locally.
By embedding this script within the <Action> element of the XML, if the CLEO system imports this configuration and executes the defined action by combining the vulnerability mentioned in CVE-2024-50623, the malicious code will run on the server. This could completely compromise the system running CLEO, given that CLEO often runs with significant privileges and access to internal systems and file shares.
Analyzing the malicious PowerShell script content
The script in question was originally invoked as remote code execution (RCE) during suspected CVE-2024-50623 exploitation:
This is a common technique used by attackers to obfuscate their malicious code. Decoding the Base64 string reveals a PowerShell snippet that:
Establishes a TCP connection to a suspicious external host (185.181.230.103) on port 443. (See additional external host indicators in the IOCs section.)
Retrieves and decrypts data from the remote server using a custom XOR-based routine.
Writes the decrypted output as a JAR file named cleo.2853.
Executes the malicious JAR using the embedded Java runtime of Cleo LexiCom (jre\bin\java.exe -jar cleo.2853).
Step-by-step analysis
Network connection setup The script begins by creating a Net.Sockets.TcpClient object and connecting it to the remote server:
A StreamWriter $w is then created, allowing the script to send initial data to the server. The malware sends the “TLS v3 <string.>” and processes the response. This serves as a form of handshake or protocol initialization.
2. XOR decryption setup Before reading any payload from the server, the script sets up key variables for decrypting data:
It continuously reads data from the remote server into $a.
For each byte, it calculates an index $j into $k (cycling through the key bytes).
It XORs the received byte with $k[$j] and a running state variable $g.
$g and $k[$j] evolve dynamically, meaning the key changes with every byte processed, making static detection harder.
Decrypted bytes are then written directly into the file cleo.2853.
The number behind the “cleo.*” differs in the cases we observed. By the end of this loop, the attacker’s encrypted payload is stored locally as a decrypted file.
4. Final steps: Executing the malicious JAR After fetching and decrypting the data, the script closes all streams and sets some environment variables:
The $env:QUERY variable appears to include additional IP addresses and contains the AES key used to decrypt the next stage and the string to send to the C2 server to receive the next payload. Finally, the script runs the malicious JAR file:
This leverages the Cleo environment’s embedded Java runtime. Since Cleo’s file transfer products come bundled with their own Java environment, the attackers don’t need to rely on a system-wide installation — they can simply run their malicious JAR directly. In one of our IR cases, the “cleo.xxxx” file was written to the C:\VLTrader\ directory.
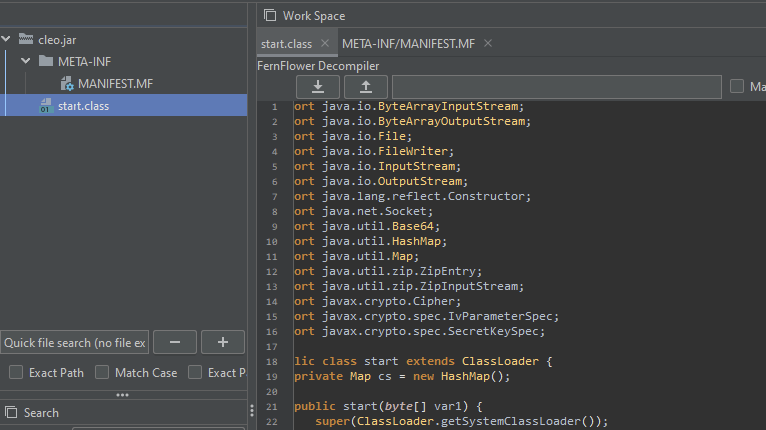
Inside the JAR file The core functionality revolves around a custom class loader named “start”.
Instead of loading classes from the file system, this loader accepts a byte array representing a compressed archive of class files. It then extracts each entry and stores them in a map, ready to be defined as Java classes on demand.
What does this custom class loader do?
Extracts classes from a byte array: The constructor of the start class takes a byte array (like a JAR) and reads the class using a ZipInputStream. Each entry is unpacked and stored in a map keyed by the entry name. For example:
ZipInputStream zis = new ZipInputStream(new ByteArrayInputStream(byteArray));
ZipEntry entry;
while ((entry = zis.getNextEntry()) != null) {
    ByteArrayOutputStream bos = new ByteArrayOutputStream();
    int read;
    while ((read = zis.read(buffer)) > 0) {
        bos.write(buffer, 0, read);
    }
    cs.put(entry.getName(), bos.toByteArray());
}
Defining Classes at Runtime: Later, when a class is requested, the findClass method checks the map. If found, it uses defineClass to load that class directly from the in-memory bytes:
if (cs.containsKey(className)) {
    byte[] classData = (byte[]) cs.get(className);
    return defineClass(className, classData, 0, classData.length);
2. Fetches and decrypts class data remotely. The main method doesn’t just run local code — it also does the following:
Reads configuration and keys from environment variables.
Connects to a remote host over port 443 and sends a “TLS v3” handshake-like message.
Receives encrypted data, which it then decrypts using AES keys derived from the environment-provided values.
Once decrypted, this data is treated like a JAR file, passed into a new start instance, and thus new classes are loaded at runtime.
3. Executes a specific class (Cli): With the new classes loaded, the code uses reflection to instantiate a particular class named “Cli” and invoke its constructor.
This mechanism allows the JAR to remain small and stealthy, as it doesn’t contain all its logic up front. Instead, it fetches critical code at runtime, decrypts it, and executes it dynamically. But it didn’t stop here — after executing this first JAR file, which acts as a loader, it downloads a zip file that contains multiple JAR files:
File name
MD5
Cli
fa0ffca3597af31fc196ca27283aa038
Dwn
510a7fa9d425f1c3a38ad81d813b3f17
DwnLevel
7dcaffc9c26fe9e08e9b66e05c644cfc
Mos
ee7acd7a8a5795308942f094c950de6f
Proc
37a761f4d02577cf6789676f87cb9fc6
ScSlot
6ff85e7bec211869073b969dbd10c8eb
SFile
ca3de6f055f94acc87c6d335d9cc5c04
Slot
d924ffd1f2952a03da29c0a7a33e6a54
SrvSlot
bcc1bf75e0be3efabbd616cc8cfa8c35
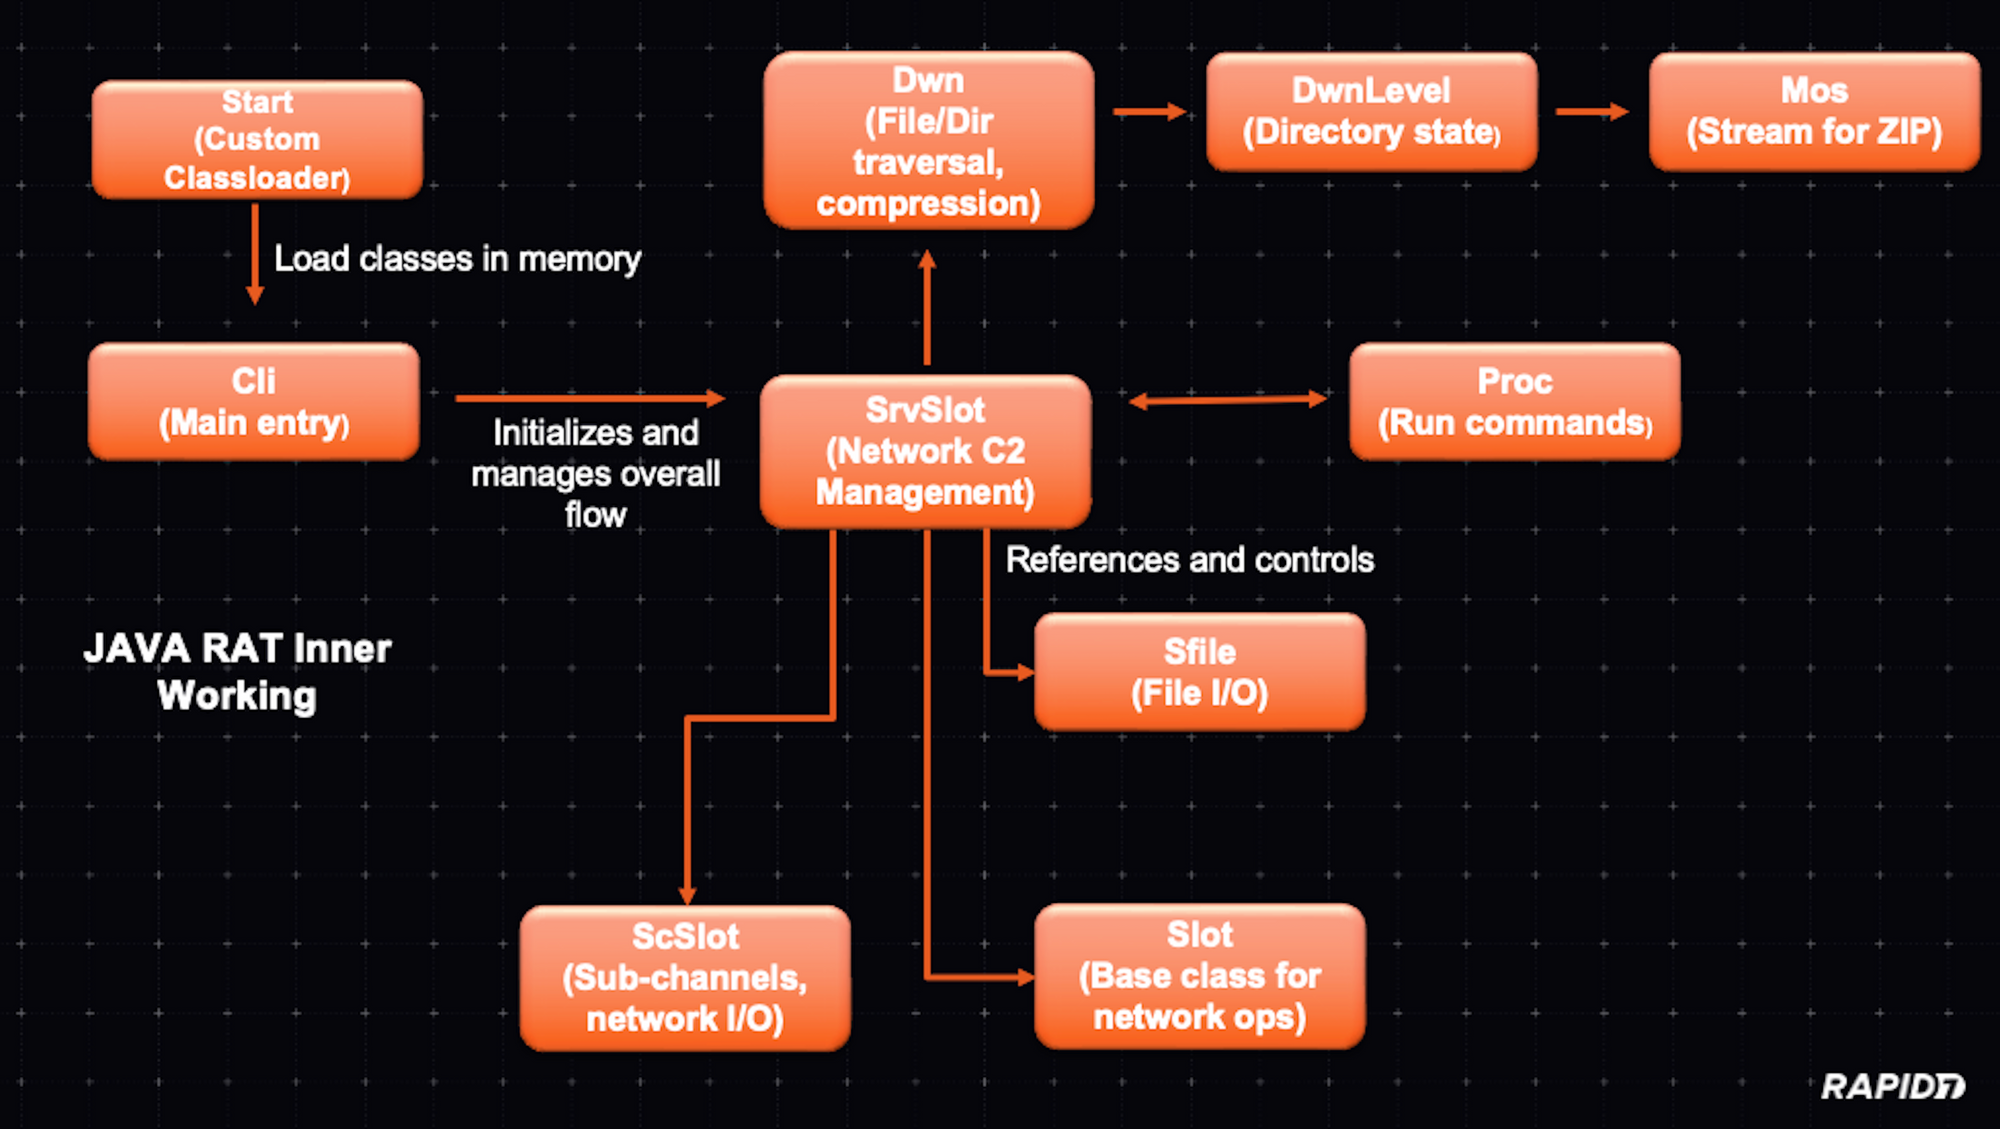
Overall this is how the modules work together and what their function is:
The Cli class appears to be a key component of a remote backdoor mechanism. On startup, it determines the operating system and sets flags accordingly before attempting to connect to a remote host over port 443 using Java’s non-blocking I/O. Once connected, it can manage data streams via asynchronous event loops, handle received data, and potentially issue commands. After initialization, the code instructs the system to delete its own initial file to remove evidence of its presence.
In Rapid7 MDR investigations into exploitation of Cleo software, we observed commands being executed that we would categorize as reconnaissance attempts.
The DWN class appears to facilitate the packaging and transmission of files from the local system to a remote server. It assembles files (and directories) into a ZIP archive on the fly, splitting them into multiple ZIP chunks if they exceed a certain size threshold. Using a SrvSlot reference, it sends compressed file data over a network channel, carefully managing buffers and limiting throughput to avoid overwhelming the connection. The code iterates through directories, queues files, and processes them incrementally, updating statistics and retrying if conditions are not ideal. Through this mechanism, this class effectively automates and streamlines the mass transfer of local files, hinting at a data exfiltration or remote backup process. It’s designed to run quietly in the background, handle large file sets, and provide periodic progress updates to its server counterpart.
The DwnLevel class is a simple helper structure that represents a single level in a file traversal hierarchy. It holds an array of file objects, along with an index and a state variable to track the current processing position. As the Dwn class iterates through directories, the DwnLevel Java class instance keeps track of which files have been processed and which remain, helping the file packaging and transfer process proceed smoothly through potentially nested directories.
The Mos class acts as a custom output stream for sending ZIP data through Dwn. Instead of writing to disk, it buffers data in memory, attaches metadata like the job ID and packet offsets, and then hands the chunks off to Dwn to send out. This setup allows code that writes ZIP entries to operate as if it were writing to a normal output stream, while the Mos and Dwn classes handle the network transmission details behind the scenes.
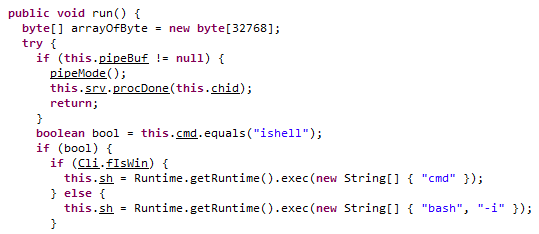
Proc is a thread that runs external commands on the system, captures their output, and sends it back through SrvSlot. It can launch interactive shells, parse configuration files, and handle input given before the process starts.
In the code of this class, we also can discover that it is cross platform designed, either executing a cmd (Windows) or bash (*nix) shell:
ScSlot manages a network connection for a specific channel. It handles connecting, reading data, and relaying it to the SrvSlot class. If the connection fails or no data is received, it signals the server to close the channel. Its tick method processes incoming data in chunks to ensure smooth communication.
The SFile class handles file reading and writing operations. It can both read from an existing file or write to a new file, depending on the flags provided. The class tracks the file size, saved size and handles errors by setting status messages.
The Slot class manages the network connection using the Java network IO class. It handles connecting, reading, and writing, ensuring a smooth data transfer.
Last but not least, since it is a core component of this Java RAT, is the SrvSlot class. It interacts with other classes as described before and is the central node for handling encrypted communications and data transfer — it handles the ZIP transfer traffic. Besides traffic handling, a small component in the code of this class appears to be for debugging purposes (i.e., providing diagnostics and session statistics).
Overall this set of Java classes provide a modular multi-stage system (Java-RAT) designed to communicate with a C2, has file-transfer and management functionality, can execute commands and applies packet level encryption/decryption.
In multiple attack chains, after initial exploitation, the adversary executed the following enumeration commands via cmd to gather user, group and system information from the impacted system and display domain trust relationships.
systeminfo
net group /domain
whoami
wmic logicaldisk get name,size
nltest /domain_trusts
Rapid7 also observed post-exploitation activity in the form of an "OverPass-The-Hash" attack, in which the adversary leverages the NTLM hash of an account to obtain a Kerberos ticket that can be used to access additional network resources within the impacted environment.
MITRE ATT&CK Enterprise Techniques
Initial access
Exploit Public-Facing Application (T1190)
Execution
Command and Scripting Interpreter (T1059)
Discovery
System Owner/User Discovery (T1033)
System Information Discovery (T1082)
Domain Trust Discovery (T1482)
Permission Groups Discovery (T1069)
Lateral movement
Use Alternate Authentication Material: Pass the Hash (T1550/002)
As published in HackerNoon and featured as a “Top 20 Best Read Article” for AI.
Introduction
The rapid advancement of AI has offered powerful tools for malware detection, but it has also introduced new avenues for adversarial attacks. As an example, recently OpenAI reported threat actors abusing ChatGPT to execute reconnaissance, help fix code, write partial code, or look at vulnerabilities. These are, to me, examples of AI aiding “basic” steps, but would threat actors invest and use more advanced applications?
Universal Adversarial Perturbations (UAPs) have gained attention due to their potential to bypass machine learning models in various domains, including malware detection. UAPs can manipulate malware in ways that evade AI-based detection systems without altering the malware’s core functionality. However, despite this capability, cybercriminals have not widely adopted AI-driven techniques like UAPs. This blog delves into the complexity and effort required to generate UAPs for malware and explains why it might not be worth the trouble for attackers.
Just to be clear on definitions:
Artificial Intelligence (AI) is a broad field that aims to create machines or software capable of performing tasks that typically require human intelligence, such as understanding language, recognizing images, problem-solving, and decision-making. AI encompasses various techniques and approaches, from rule-based systems to learning algorithms.
Machine Learning (ML) is a subset of AI that focuses on building systems that learn from data. Instead of being explicitly programmed for each task, ML models identify patterns in data to make predictions or decisions, improving over time with more experience.
UAPs: A Brief Overview
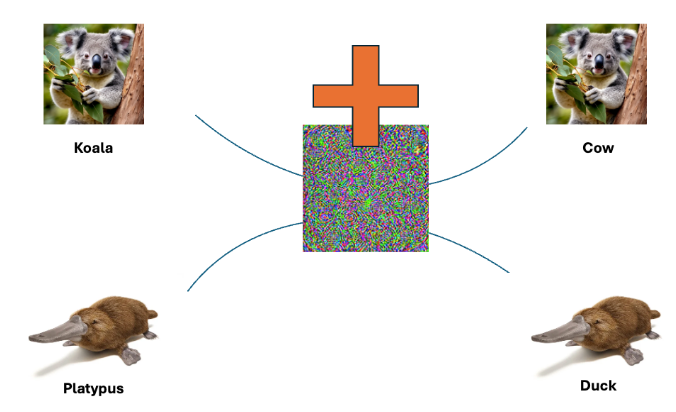
Universal Adversarial Perturbations (UAPs) are subtle modifications applied to input data (such as malware samples) to mislead AI models. What makes UAPs particularly interesting is that a single perturbation can be applied to many inputs (one ring rules them all), causing the AI model to misclassify them. Think of it as changing just a few pixels in a picture to make a powerful facial recognition system mistake someone for someone else. In the below example, a single bit of random code is added to multiple different images, resulting in the classifying model going completely wrong on the identification.
When we look at the example of the platypus, the model identifies the animal partially right based on the training on the beak with other images, but due to the interference with the added “noise” in the pixels, it classifies it wrong. That is exactly the interesting space when it comes to malware detection and evasion. You want malicious files to be classified wrong.
In the context of malware detection, UAPs allow attackers to evade detection without having to create entirely new malware variants. While this seems like a low-effort, high-reward strategy, generating effective UAPs is far more challenging than it appears, particularly in the malware domain.
Complexity in Crafting UAPs for Malware
In their paper, “Realizable Universal Adversarial Perturbations for Malware,” Labaca-Castro et al. demonstrate that crafting UAPs for malware requires an intricate balance between manipulating feature space (abstract representations of malware) and problem space (real-world executable malware). Unlike image or text data, where perturbations may be easily applied without affecting functionality, malware is far more delicate. A slight misstep in the perturbation process can corrupt the malware sample, rendering it unusable. You need to respect (with regards to Windows malware) the PE structure of a file. A modification to that structure will break its functionality and the malware will not execute. It may have bypassed detection but it is useless to the attacker.
The process requires attackers to perform a series of careful transformations to avoid breaking the executable while still evading detection. This is a far cry from simply adding noise to an image or text dataset. As a result, the time and expertise required to create UAPs that both fool AI/ML malware detection models and preserve malware functionality is significant.
UAPs vs. New Malware Variants
Given the complexity of generating UAPs, cybercriminals face a dilemma: Should they invest time and resources into crafting these perturbations, or is it easier to create entirely new strains of malware?
Developing a new malware strain might involve reusing code from previous versions, applying known obfuscation techniques, or modifying payloads. This process is often faster, less risky, and more predictable compared to the complex sequence of transformations required to generate UAPs. As a result, many attackers prefer to invest in creating new strains of malware, which are more likely to achieve the desired outcome without the same level of effort and risk.
Challenges
One of the major hurdles in applying UAPs to malware is the real-world execution environment. Malware operates in dynamic, unpredictable conditions, and UAPs crafted in controlled environments may not perform as expected once deployed. Small changes in the operating system, file structure, or antivirus defenses can render the UAP ineffective. This fragility is a key reason why UAPs remain largely theoretical for malware attacks rather than a widely adopted technique in practice.
Additionally, defenders are not standing still. Adversarial training—where AI models are retrained using adversarial examples—can harden systems against UAPs, making it even harder for attackers to succeed. Mitigation strategies will raise the cost and effort required for attackers to generate successful UAPs, further reducing their appeal.
Conclusion
The idea of using AI to defeat AI, particularly through Universal Adversarial Perturbations, may seem like a natural progression in the ongoing battle between attackers and defenders. However, the reality is that the complexity and risk associated with developing UAPs for malware make this approach unattractive for most cybercriminals. Instead, attackers tend to rely on more straightforward methods like creating new malware variants, which offer a better return on investment with less risk of failure. If you examine some of the latest ransomware campaigns, none of them highlight the use of AI-based techniques. Instead, as shown in recent coverage of ransomware tactics, attackers consistently focus on tried-and-tested approaches that maximize impact and minimize operational complexity.
As long as the development of UAPs remains fraught with difficulties—such as maintaining functionality and overcoming problem-space constraints—it’s unlikely that we will see widespread adoption of these techniques in the cybercriminal world. Instead, traditional malware development and deployment methods will continue to dominate the landscape, while defenders must remain vigilant and adaptive to the evolving AI threat landscape.
The sale and purchase of unauthorized access to compromised enterprise networks has become a linchpin for cybercriminal operations, particularly in facilitating ransomware attacks. Underground forums are sharing guidelines on breaching networks and selling the access they obtain, leaving the exploitation to other malicious actors.
On underground criminal forums, these transactions allow actors with complementary skills to collaborate, amplifying the impact and reach of cyberattacks. The market for such access has grown notably, especially as ransomware operators increasingly employ double-extortion tactics. A foothold in a victim’s network, with credentials that enable stealthy operations, has never been a more lucrative — and popular — business model.
Organizations across all sectors and regions are vulnerable and a target. The collective shift to remote work during the COVID-19 pandemic has expanded the attack surface, as more remote access tools remain in use to this day. In our 2024 Attack Intelligence Report, we noted that 36% of all widespread threat events Rapid7 tracked in 2023 involved the exploitation of network edge device vulnerabilities. This trend has continued into 2024.
In this blog, we delve into a major forum frequented by ransomware actors and affiliates, called RAMP. As part of our research for the Rapid7 Ransomware Radar Report, we analyzed RAMP postings offering corporate access from January 1, 2024 to June 30, 2024, uncovering 4 key trends within this underground marketplace.
The forum: RAMP
Re-launched/branded in July 2021, the RAMP (Ransomware and Advanced Malware Protection) forum is an underground cybercriminal hub originally known as Payload.bin, tracing its roots back to 2012 when it first operated on the Tor network. With a primary focus on ransomware, RAMP is a multilingual platform catering to Russian, Chinese, and English speakers and boasts over 14,000 registered members. Access to RAMP is highly restricted; potential users must have been active members on the XSS and Exploit forums for at least two months, have posted at least ten times, and maintain a good reputation, or alternatively, pay a $500 registration fee for anonymity.
RAMP serves as both a forum and a marketplace, offering ransomware kits, malware, and stolen data, while also providing comprehensive guides and tutorials for cyberattacks. It facilitates ransomware-as-a-service (RaaS) operations, enabling affiliates to deploy ransomware for a share of the profits. Despite its high registration fee, a stark contrast to the $120 annual fee for premium XSS users, RAMP’s closed community is a critical resource for many threat actors. The forum’s design mimics Silk Road-like darknet markets, including escrow features, and it operates primarily off-the-record to avoid law enforcement detection. Its administrator claims an annual revenue of around $250,000, benefiting from its predominantly Russian user base and a strict policy against selling certain illegal goods and services.
Selling Access
To investigate the trends and context around the selling of access into corporate networks, we analyzed all the postings on the RAMP forum from January through June 2024. Some of these posts were cross-posted on other underground forums as well. In most of the cases, the initial access was mentioned and/or the price asked. Where this data was not available, we classified that as ‘unknown’ in our dataset for analysis.
So what are some of the trends we discovered?
Trend #1: Country Distribution
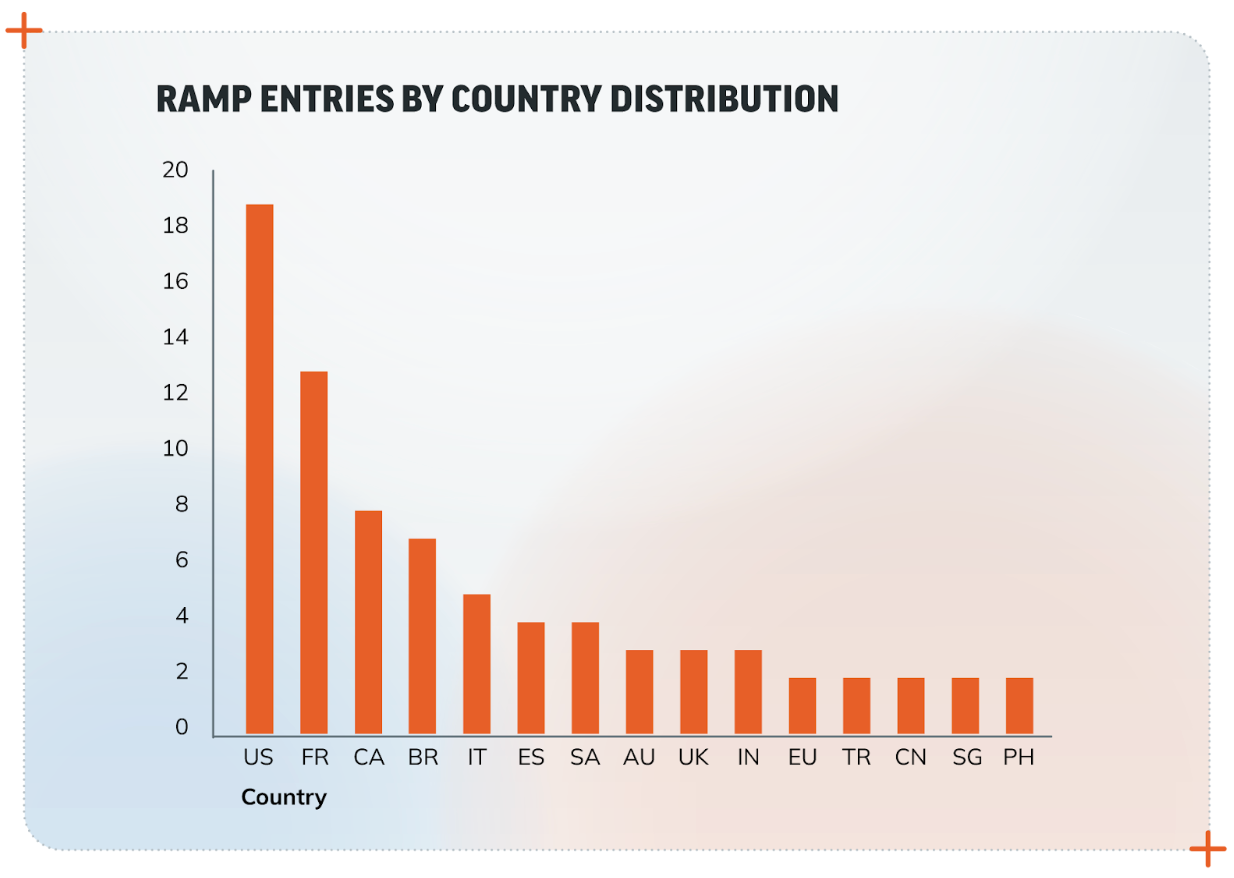
The United States leads the pack with the highest number of entries referencing the country of the company attackers have credentials or access to, followed by France and Brazil. Companies based in Western countries command a higher price due to their perceived wealth and easier access to resources for payment, so what we’re seeing thus far in 2024 (per the chart below) is what would be expected. The only exception to this is Brazil, likely due to Brazilian affiliates that target larger Brazilian businesses.
Trend #2: Revenue Distribution
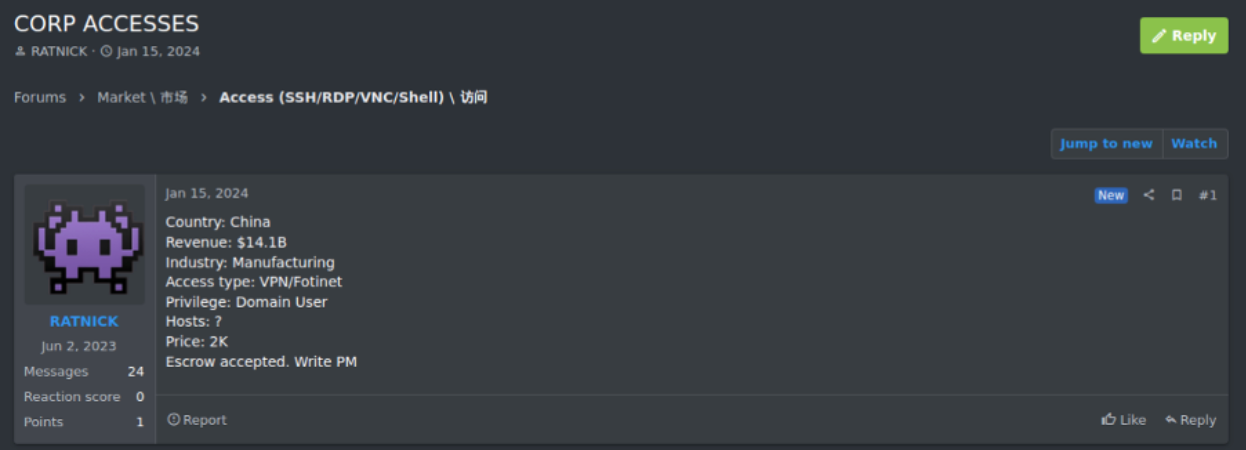
One of the variables that determine the asking price for network access is the revenue made by the target. Very often, sites like ZoomInfo are used to look up the annual revenue, which is then mentioned in the posting, as in our example below.
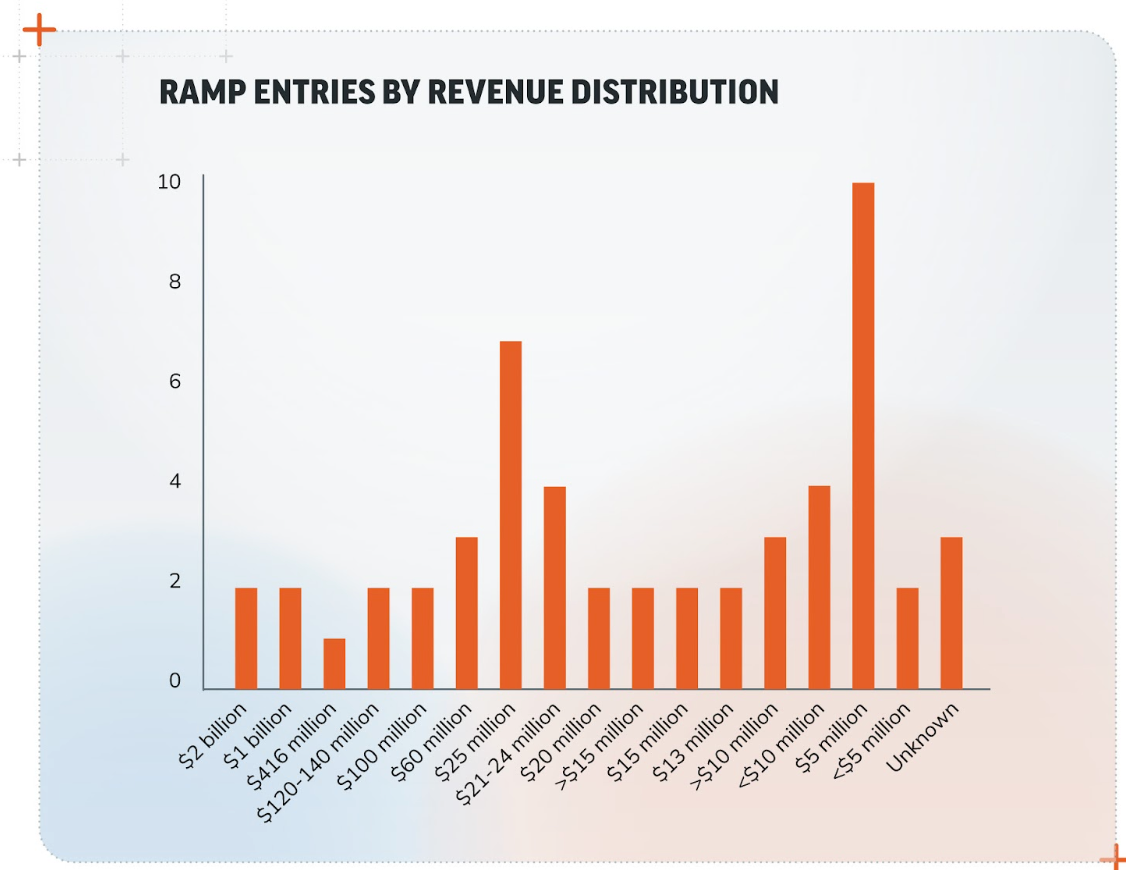
As the chart below shows, we observed a broad range of revenue values within the RAMP dataset, where some entries specified exact amounts and others used ranges. A significant number of entries included revenues in the millions, particularly around $5 million USD.
In fact, companies with revenues in the $5 million range appeared twice as often as those in the $30-50 million range and 5 times more frequently than those with a $100 million revenue. This could indicate that such companies are large enough to hold valuable data but perhaps not as well protected as larger corporations. Regardless, this finding shows that companies with $5 million in revenue are attractive targets and represents an interesting shift from access brokers only targeting the “big fish.”
Trend #3: Access Type Distribution
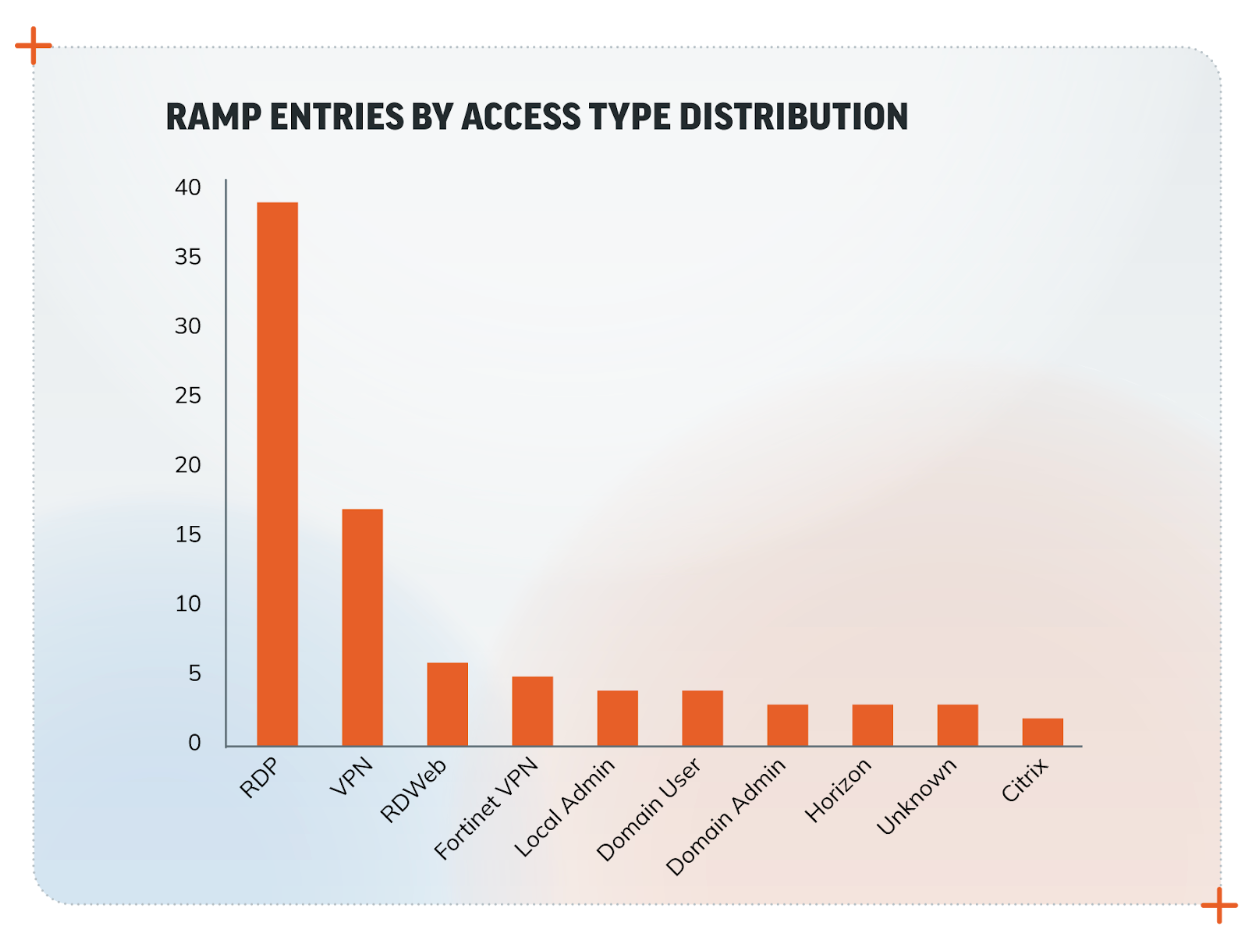
How are threat actors getting in? Our analysis shows that Remote Desktop Protocol (RDP) is the most common access type, followed by VPN. VPN presents a greater possibility of remaining undetected. That, in combination with the level of access (user or privileged user), demands a higher price.
RDP is often used for remote work and system management, and it can be a significant vulnerability if not properly secured. The prevalence of RDP underscores the importance of securing remote access points.
As noted in our 2024 Attack Intelligence Report, missing or unenforced multi-factor authentication (MFA) gave rise to 41% of the incidents Rapid7 MDR observed in 2023. Companies should ensure robust security measures like MFA and proper network segmentation to protect RDP endpoints. Also, if we consider the combined value of VPN and such technologies, then the trend of targeting network edge devices will certainly continue.
Trend #4: Price Distribution
Many RAMP entries list unknown prices. Among the known prices, amounts like $500, $800, and $1000 are common. Company revenue, headquarter location, and the type of access are each a basis for how the threat actor formulates their asking price, which can range widely based on the perceived value of the target network. It is common for prices to spike based on the specific attributes of the target (e.g., revenue, security posture, type of data accessible).
Conclusion
Our analysis highlights key areas of concern for companies looking to protect themselves against access brokers. Businesses in the US, France, and Brazil, as well as those with revenues around $5 million, should be particularly vigilant. Securing remote access points, investing in robust solutions, and understanding the pricing dynamics of the black market for network access can help companies bolster their defenses against this pervasive threat.
Last year was not a year for the faint of heart. Organizations of every size found themselves faced with ransomware attacks at varying levels of sophistication, yet every one of them was damaging. And as we step into 2024, the first victims of ransomware attacks are already being reported. What can the 2023 ransomware stats tell us about the year that was, and how can we use them to plan for the year ahead?
In this blog we will dissect the multifaceted dimensions of ransomware attacks observed in 2023, providing insights and looking a bit forward to what 2024 might bring. For our data analytics, we make use of publicly available data (like posts from the ransomware groups themselves) and 2023 ransomware incident data from our MDR team, both of which we’ve enriched with context from the data gathered in Rapid7 Labs.
The 2023 Ransomware Landscape
Most ransomware groups have leak sites where they announce victims of their campaigns. These leak sites are a tactic to put more pressure on their victims to pay the ransom; if the ransom is not paid, they will leak the compromised data via that site. The frequency of posts is a good indicator of how often and which groups are active, but the ransomware landscape is larger than that.
The number of unique ransomware families these groups utilized in 2023 decreased by more than half, from 95 new families in 2022 to 43 in 2023. This tells us that the “current” ransomware families and models are working/profitable and there’s no need to develop something brand new.
Our combined sources uncovered nearly 5200 reported ransomware cases throughout the course of 2023. In reality, we believe that number was actually higher because it doesn’t account for the many attacks that likely went unreported.
Coveware, a security consulting firm, found that the average ransom payment for Q3 2023 was $850,700 USD. That is only the amount paid for the ransom; the real costs for recovering of a ransomware incident are based on a range of factors that include:
Downtime
Damage to reputation
Lost business
Labour hours
Increased insurance coverage costs
Legal counseling and settlement fees
The same report mentioned a staggering 41% of victims opted to pay the ransom.
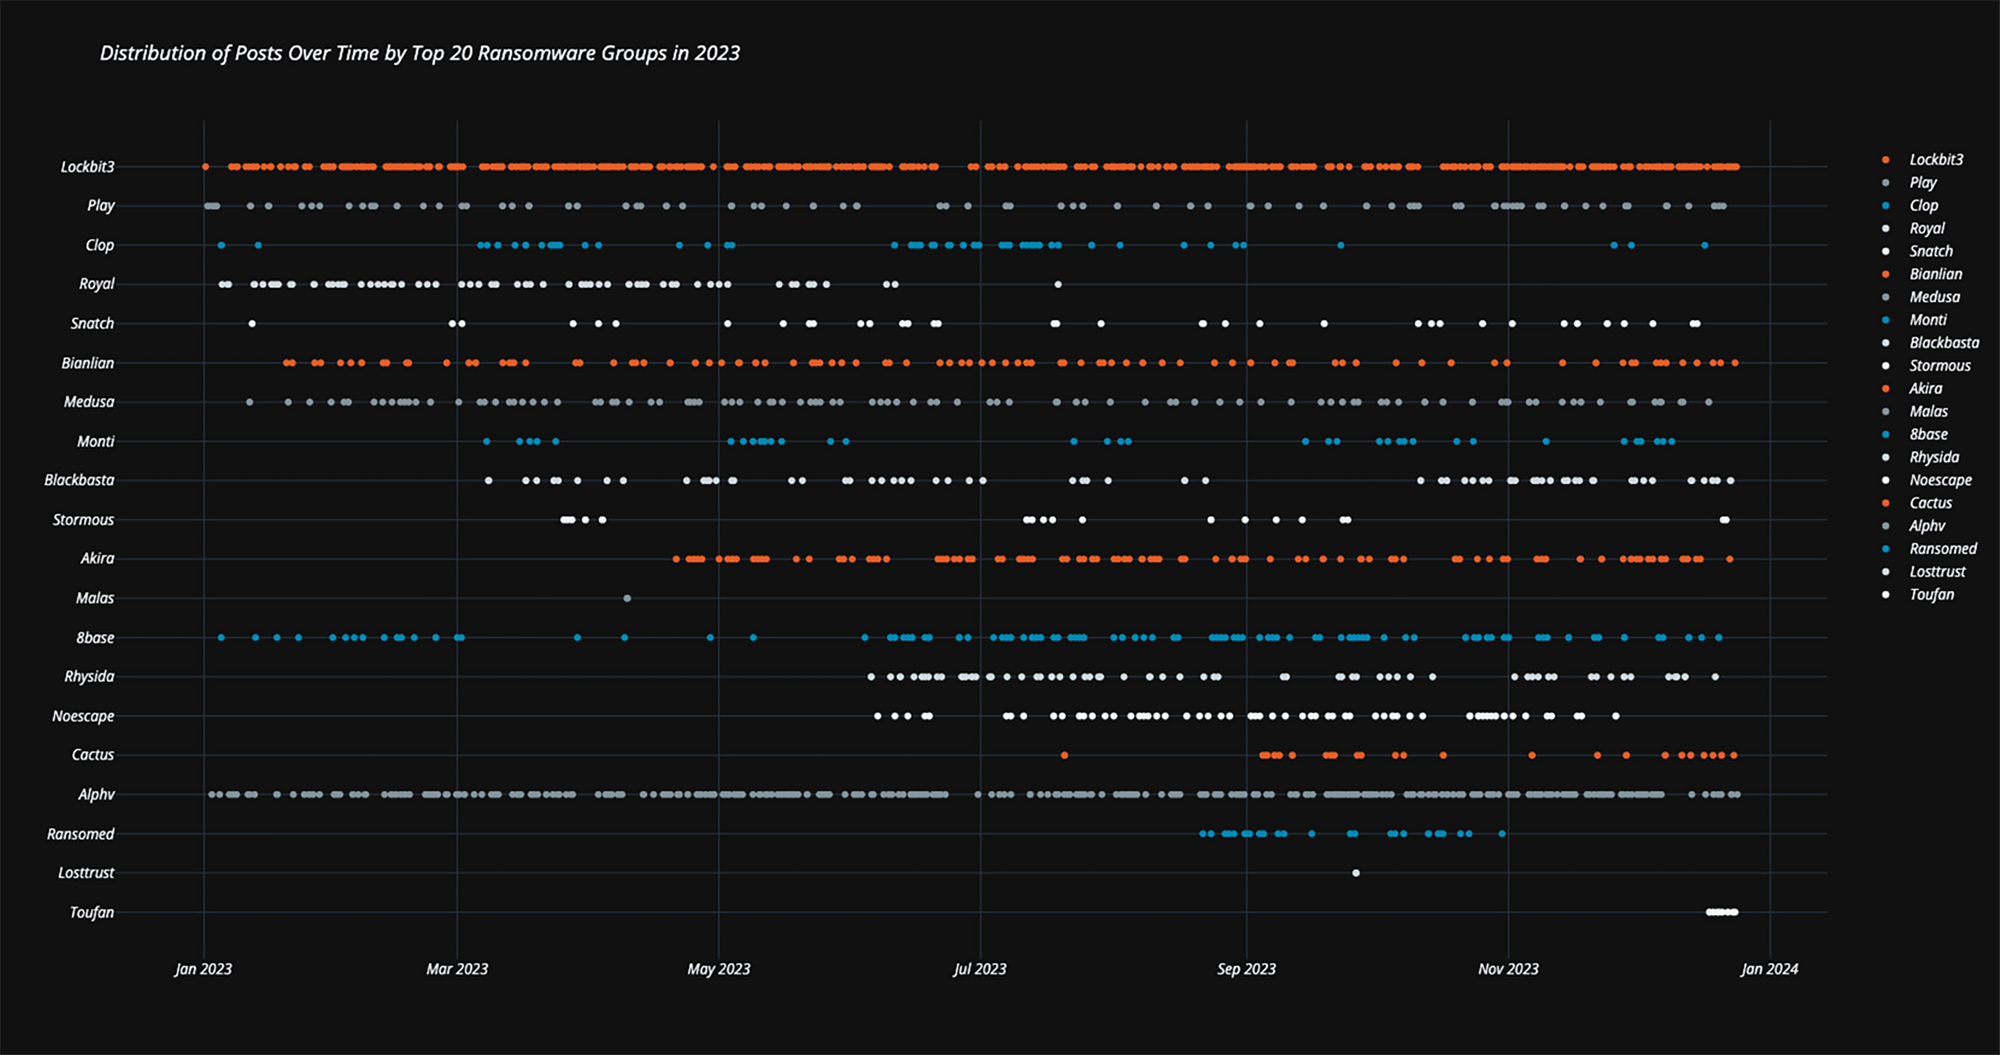
The below scatter plot shows the number of ransomware incidents attributed to the top 20 ransomware groups for 2023, based on leak site communications, public disclosures, and Rapid7 incident response data.
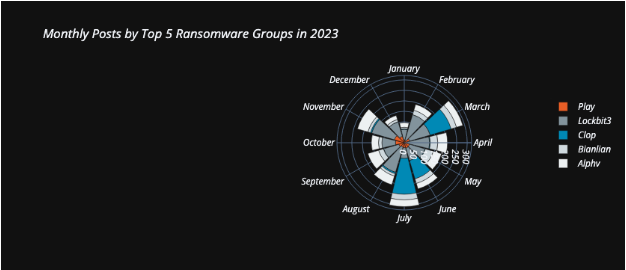
Zooming in on the most active groups (supported by a large ecosystem of initial access brokers), the top 5 groups we identified are:
Alphv aka BlackCat ransomware
BianLian
Cl0P
Lockbit(3)
Play
The below polar-bar chart visualizes these groups’ frequency of postings per month on their leak sites:
2023 Ransomware Attacks
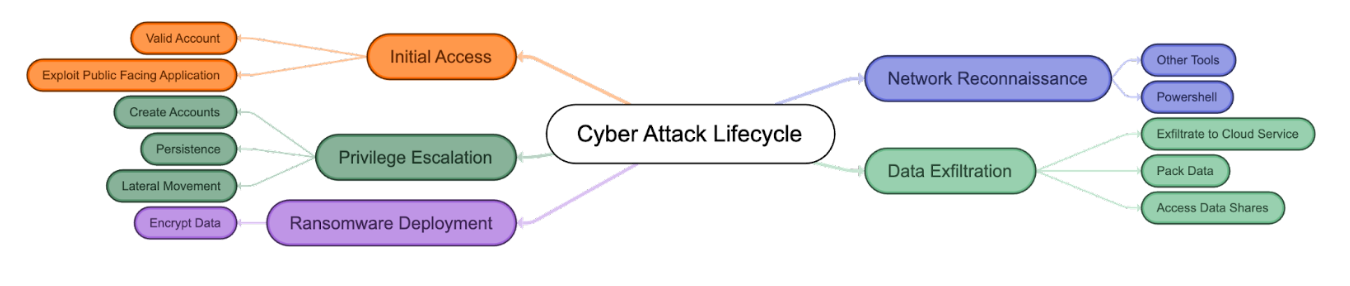
Rapid7 Labs conducted an analysis of the 2023 ransomware attacks using data sourced from both external and internal reports. We compared the modus operandi of these attacks and mapped them out against the MITRE ATT&CK model. The results are visualized in the following diagram:
This diagram effectively encapsulates the common patterns and methodologies observed in the majority of ransomware attacks. It serves as a visual representation, outlining the sequence of steps typically followed by attackers from initial breach to final ransom demand. In our statistics, exploiting a public facing application and having a valid account are the top initial attack vectors we observed in ransomware-focused attacks in 2023.
Ransomware Groups That Came and Went
In 2023, several ransomware groups ceased their operations or underwent significant transformations. Hive ransomware marked the year’s start with its disruption in January. BlackByte, after briefly reappearing with a new white logo, went offline for the last two months of 2023.
Royal ransomware rebranded itself as Black Suit, as evidenced by the matching binaries.They took down their victim portal and started posting more on their Black Suit leak site.
Vice Society, another group, became inactive for over three months, taking down their main and backup leak sites.
NoEscape, previously known as Avaddon, executed an exit scam, further indicating the volatile and shifting landscape of ransomware groups in 2023. An “exit scam” is a fraudulent scheme where a business or individual collects funds or assets from customers or investors and then suddenly ceases operations, disappearing with the collected funds.
Who To Watch For in 2024
We anticipate that the top 5 groups mentioned will still be active in 2024; however, during the course of 2023, new groups surfaced that are interesting to watch. In random order: Cactus, Rhysida, 8base, Hunters International, Akira, and the recently surfaced Werewolves group are those to keep an eye out for.
Digital Imaging and Communications in Medicine (DICOM) is the international standard for the transmission, storage, retrieval, print, and display of medical images and related information. While DICOM has revolutionized the medical imaging industry, allowing for enhanced patient care through the easy exchange of imaging data, it also presents potential vulnerabilities when exposed to the open internet.
About five years ago, I was in the hospital while an ultrasound was taken of my pregnant wife. While the doctor made the images, a small message on the screen got my attention: “writing image to disk – transfer DICOM.” Digging into the DICOM standard at the time resulted in being able to discover exposed systems over the internet, retrieve medical images, use demo software, and 3D-print a pelvis. An example of that research is still available online here. It’s now five years later, so I was curious to see if things had changed (and no worries—I will not 3D-print another body part 😉).
This article delves into the risks associated with the unintended exposure of DICOM data and the importance of safeguarding this data.
Understanding DICOM
DICOM is more than just an image format; it encompasses a suite of protocols that allow different medical imaging devices and systems, such as MRI machines, X-ray devices, and computer workstations, to communicate with each other. A typical DICOM file not only contains the image but also the associated metadata, which may have patient demographic information, clinical data, and sometimes even the patient’s full name, date of birth, and other personal identifiers.
What Are the Exposure Risks?
Breach of Patient Confidentiality: The most pressing concern is the breach of patient confidentiality. If DICOM data is exposed online, there’s a high risk of unauthorized access to sensitive patient information. Such breaches have the potential to result in legal consequences, financial penalties, and damage to the reputations of medical institutions.
Data Manipulation: An unprotected system might allow malicious entities not only to view but also to alter medical data. Such manipulations have the potential to lead to mis-diagnoses, inappropriate treatments, or other medical errors.
Ransomware Attacks: In recent years, healthcare institutions have become prime targets for ransomware attacks. Exposing DICOM data could potentially provide a gateway for cybercriminals to encrypt vital medical information and demand a ransom for its release.
Data Loss: Without proper security measures, data could be accidentally or maliciously deleted, leading to loss of crucial medical records.
Service Interruptions: Unprotected DICOM servers could be vulnerable to denial-of-service (DoS) attacks, disrupting medical services and interfering with patient care.
Research
While previously I focused on the imaging part of the protocol, this time I looked into the possibility of retrieving PII data* from openly exposed DICOM servers.
Using Sonar, Rapid7’s proprietary internet scan engine, a study was conducted to scan for the DICOM port exposed to the internet. Using the output of the scan, a simple Python script was created that used the IP addresses discovered as input, whereby a basic set of DICOM descriptors from the “PATIENT” root-level were queried. The standard itself is very extensive and contains many fields that can be retrieved, such as PII related data including name, date of birth, comments on the treatment, and many more.
Unfortunately, we were able to quickly retrieve sensitive patient information. No need for authentication; we received the information simply by requesting it. The following screenshot is an example of what we retrieved, with the PII altered for privacy purposes.
In some cases, we were able to get more details on the study and status of the patient:
Importantly, our results not only discovered hospitals, but also private practice and veterinary clinics.
When scanning for systems connected to the internet, we focused on the two main TCP ports: TCP port 104 and TCP port 11112. We ignored the TCP port 4242 since that is mostly used to send images. In total we discovered more than 3600 results that replied to these two ports.
Although it might be interesting to geolocate where these systems are, we believe that it is better to investigate which systems are really possible candidates that we can retrieve data from and geolocate those.
TCP port 104 stats
After retrieving the list of IP addresses that responded to the open port and matched a DICOM reply, we scanned the list by using a custom script that would query if a connection could be established or not. The following diagram shows the results of this scan.
In 45% of cases, the remote server was accepting a connection that could be used for retrieving information.
TCP port 11112 stats
Next, we used the list of IP addresses that responded to a DICOM ping reply on TCP port 1112. Again we used our script to query if a connection could be established or not. The diagram below shows the results of this particular scan.
Of the total number of 1921 discovered systems responding to our DICOM connection verification script, 43% of these systems were accepting a connection that could be used for retrieving data.
Since we now know how many systems are connected, accepting connections to retrieve the information, let’s map those out on a global map, where each orange colored country is a country where systems were discovered:
Not much seems to have changed since my initial research in 2018; even searching for medical images using a fairly simple Google query results in the ability to download images from DICOM systems, including complete MRI sets. The image below showcases an innocent example from a veterinary clinic where an X-ray of an unfortunate pet was made.
Conclusion
While DICOM has proven invaluable in the world of medical imaging, its exposure to the internet poses significant risks. Healthcare institutions are the prime targets of threat actors; therefore, these risks have detrimental implications on patients’ healthcare services and consumer trust, and they cause legal and financial damage to healthcare providers.
It’s essential for healthcare institutions to recognize these risks and implement robust measures to protect both patient data and their reputations. As the cyber landscape continues to evolve, so too must the defenses that guard against potential threats. Healthcare organizations should make it a part of their business strategy to regularly scan their exposure to the internet and institute robust protections against potential risks.
*Note: Where possible, Rapid7 used their connections with National CERTS to inform them of our findings. All data that was discovered has been securely removed from the researcher’s system.
This week is the Virus Bulletin Conference in London. Part of the conference is the Cyber Threat Alliance summit, where CTA members like Rapid7 showcase their research into all kinds of cyber threats and techniques.
Traditionally, when we investigate a campaign, the focus is mostly on the code of the file, the inner workings of the malware, and communications towards threat actor-controlled infrastructure. Having a background in forensics, and in particular data forensics, I’m always interested in new ways of looking at and investigating data. New techniques can help proactively track, detect, and hunt for artifacts.
In this blog, which highlights my presentation at the conference, I will dive into the world of Shell Link files (LNK) and Virtual Hard Disk files (VHD). As part of this research, Rapid7 is releasing a new feature in Velociraptor that can parse LNK files and will be released with the posting of this blog.
VHD files
VHD and its successor VHDX are formats representing a virtual hard disk. They can contain contents usually found on a physical hard drive, such as disk partitions and files. They are typically used as the hard disk of a virtual machine, are built into modern versions of Windows, and are the native file format for Microsoft’s hypervisor, Hyper-V. The format was created by Connectix for their Virtual PC, known as Microsoft Virtual since Microsoft acquired Connectix in 2003. As we will see later, the word “Connectix” is still part of the footer of a VHD file.
Why would threat actors use VHD files in their campaigns? Microsoft has a security technology that is called “Mark of the Web” (MOTW). When files are downloaded from the internet using Windows, they are marked with a secret Zone.Identifier NTFS Alternate Data Stream (ADS) with a particular value called the MOTW. MOTW-tagged files are restricted and unable to carry out specific operations. Windows Defender SmartScreen, which compares files with an allowlist of well-known executables, will process executables marked with the MOTW. SmartScreen will stop the execution of the file if it is unknown or untrusted and will alert the user not to run it. Since VHD files are a virtual hard-disk, they can contain files and folders. When files are inside a VHD container, they will not receive the MOTW and bypass the security restrictions.
Depending on the underlying operating system, the VHD file can be in FAT or NTFS. The great thing about that is that traditional file system forensics can be applied. Think about Master-File_Table analysis, Header/Footer analysis and data carving, to name a few.
Example case:
In the past we investigated a case where a threat-actor was using a VHD file as part of their campaign. The flow of the campaign demonstrates how this attack worked:
After sending a spear-phishing email with a VHD file, the victim would open up the VHD file that would auto-mount in Windows. Next, the MOTW is bypassed and a PDF file with backdoor is opened to download either the Sednit or Zebrocy malware. The backdoor would then establish a connection with the command-and-control (C2) server controlled by the threat actor.
After retrieving the VHD file, first it is mounted as ‘read-only’ so we cannot change anything about the digital evidence. Secondly, the Master-File-Table (MFT) is retrieved and analyzed:
Besides the valuable information like creation and last modification times (always take into consideration that these can be altered on purpose), two of the files were copied from a system into the VHD file. Another interesting discovery here is that the VHD disk contained a RECYCLE.BIN file that contained deleted files. That’s great since depending on the filesize of the VHD (the bigger, the more chance that files are not overwritten), it is possible to retrieve these deleted files by using a technique called “data carving.”
Using Photorec as one of the data carving tools, again the VHD file is mounted read-only and the tool pointed towards this share to attempt to recover the deleted files.
After running for a short bit, the deleted files could be retrieved and used as part of the investigation. Since this is not relevant for this blog, we continue with the footer analysis.
Footer analysis of a VHD file
The footer, which is often referred to as the trailer, is an addition to the original header that is appended to the end of a file. It is a data structure that resembles a header.
A footer is never located at a fixed offset from the beginning of an image file unless the image data is always the same size because by definition it comes after the image data, which is typically of variable length. It is often situated a certain distance from the end of a picture file. Similar to headers, footers often have a defined size. A rendering application can use a footer’s identification field or magic number, like a header’s, to distinguish it from other data structures in the file.
When we look at the footer of the VHD file, certain interesting fields can be observed:
These values are some of the examples of the data structures that are specified for the footer of a VHD file, but there are also other values like “type of disk” that can be valuable during comparisons of multiple campaigns by an actor.
From the screenshot, we can see that “conectix” is the magic number value of the footer of a VHD file, you can compare it to a small fingerprint. From the other values, we can determine that the actor used a Windows operating system, and we can derive from the HEX value the creation time of the VHD file.
From a threat hunting or tracking perspective, these values can be very useful. In the below example, a Yara rule was written to identify the file as a VHD file and secondly the serial number of the hard drive used by the actor:
Shell link files (LNK), aka Shortcut files
A Shell link, also known as a Shortcut, is a data object in this format that houses data that can be used to reach another data object. Windows files with the “LNK” extension are in a format known as the Shell Link Binary File Format. Shell links can also be used by programs that require the capacity to store a reference to a destination file. Shell links are frequently used to facilitate application launching and linking scenarios, such as Object Linking and Embedding (OLE).
LNK files are massively abused in multiple cybercrime campaigns to download next stage payloads or contain code hidden in certain data fields. The data structure specification of LNK files mentions that LNK files store various information, including “optional data” in the “extra data” sections. That is an interesting area to focus on.
Below is a summarized overview of the Extra Data structure:
The ‘Header’ LinkInfo part contains interesting data on the type of drive used, but more importantly it contains the SerialNumber of the hard drive used by the actor when creating the LNK file:
Other interesting information can be found; for example, around a value with regards to the icon used and in this file used, it contains an interesting string.
Combining again that information, a simple Yara rule can be written for this particular LNK file which might have been used in multiple campaigns:
One last example is to look for the ‘Droids’ values in the Extra Data sections. Droids stands for Digital Record Object Identification. There are two values present in the example file:
The value in these fields translates to the MAC address of the attacker’s system… yes, you read this correctly and may close your open mouth now…
Also this can be used to build upon the previous LNK Yara rule, where you could replace the “.\\3.jpg” part with the MAC address value to hunt for LNK files that were created on that particular device with that MAC address.
In a recent campaign called “Raspberry Robin”, LNK files were used to distribute the malware. Analyzing the LNK files and using the above investigation technique, the following Yara rule was created:
Velociraptor LNK parser
Based on our research into LNK files, an updated LNK parser was developed by Matt Green from Rapid7 for Velociraptor, our advanced open-source endpoint monitoring, digital forensics, and cyber response platform.
With the parser, multiple LNK files can be processed and information can be extracted to use as an input for Yara rules that can be pushed back into the platform to hunt.
Windows.Forensics.Lnk parses LNK shortcut files using Velociraptor’s built-in binary parser. The artifact outputs fields aligning to Microsoft’s ms-shllink protocol specification and some analysis hints to assist review or detection use cases. Users have the option to search for specific indicators in key fields with regex, or control the definitions for suspicious items to bubble up during parsing.
Some of the default targeted suspicious attributes include:
Large size
Startup path location for auto execution
Environment variable script — environment variable with a common script configured to execute
No target with an environment variable only execution
Suspicious argument size — large sized arguments over 250 characters as default
Arguments have ticks — ticks are common in malicious LNK files
Arguments have environment variables — environment variables are common in malicious LNKs
Arguments have rare characters — look for specific rare characters that may indicate obfuscation
Arguments that have leading space. Malicious LNK files may have many leading spaces to obfuscate some tools
Arguments that have http strings — LNKs are regularly used as a download cradle
Suspicious arguments — some common malicious arguments observed in field
Suspicious trackerdata hostname
Hostname mismatch with trackerdata hostname
Due to the use of Velociraptor’s binary parser, the artifact is significantly faster than other analysis tools. It can be deployed as part of analysis or at scale as a hunting function using the IOCRegex and/or SuspiciousOnly flag.
Summary
It is worth investigating the characteristics of file types we tend to skip in threat actor campaigns. In this blog I provided a few examples of how artifacts can be retrieved from VHD and LNK files and then used for the creation of hunting logic. As a result of this research, Rapid7 is happy to release a new LNK parser feature in Velociraptor and we welcome any feedback.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.