All posts by Jeremy Hartman

Code Orange: Fail Small is complete. The result is a stronger Cloudflare network

Post Syndicated from Jeremy Hartman original https://blog.cloudflare.com/code-orange-fail-small-complete/

Over the past two and a bit quarters, we’ve undertaken an intensive engineering effort, internally code-named “Code Orange: Fail Small“, focused on making Cloudflare’s infrastructure more resilient, secure, and reliable for every customer.

Earlier this month, the Cloudflare team finished this work.

While improving resiliency will never be a “job done” and will always be a top priority across our development lifecycle, we have now completed the work that would have avoided the November 18, 2025 and December 5, 2025 global outages.

This work focused on several key areas: safer configuration changes, reducing the impact of failure, and revising our “break glass” procedures and incident management. We also introduced measures to prevent drift and regressions over time, and strengthened the way we communicate to our customers during an outage.

Here we explain in depth what we shipped, and what it means for you.

Safer configuration changes

What it means for you: In most cases, Cloudflare internal configuration changes no longer reach our network instantly and are instead rolled out progressively with real-time health monitoring. This allows our observability tools to catch problems and revert issues before they affect your traffic.

In order to catch potentially dangerous deployments before they reach production, we’ve identified high-risk configuration pipelines, and built new tools to manage configuration changes better.

For products that run on our network processing customer traffic and receive configuration changes, we no longer deploy these changes instantly across the network. Instead, relevant teams have adopted a “health-mediated deployment” methodology, the same we use when releasing software, for all configuration deployments. This includes but is not limited to the product teams that were directly affected by the incidents.

Central to this is a new internal component we call Snapstone, which we built to bring health-mediated deployment to configuration changes. Snapstone is a system that bundles configuration change into a package, and then allows gradual release of the configuration change with health mediation principles. Before Snapstone, applying this methodology to config was possible but difficult. It required significant per-team effort and wasn’t consistently applied across the network. Snapstone closes this gap by providing a unified way to bring progressive rollout, real-time health monitoring, and automated rollback to configuration deployments by default.

What makes Snapstone particularly powerful is its flexibility. Rather than being a fix for specific past failures, Snapstone allows teams to dynamically define any unit of configuration that needs health mediation, whether that’s a data file like the one that caused the November 18 outage, or a control flag in our global configuration system like the one involved in the December 5 outage. Teams create these configuration units on demand, and Snapstone ensures they are deployed safely everywhere they’re used.

This gives us something we didn’t have before: when a risk review or operational experience identifies a dangerous configuration pattern, the fix is straightforward — bring it into Snapstone, and the configuration pattern immediately inherits safe deployment. 

Reducing the impact of failure

What it means for you: In the event an issue is observed on our network, our systems now fail more gracefully. This vastly reduces the potential impact radius, to ensure your traffic is delivered even in worst-case scenarios.

Product teams have carefully reviewed, both in a manual and programmatic fashion, their potential failure modes for products that are critical for serving customer traffic. Teams have removed non-essential runtime dependencies and implemented better failure modes. We will now use the last known good configuration where possible (“fail stale”), and if that isn’t possible we have reviewed each failure case and implemented “fail open” or “fail close” depending on whether serving traffic with reduced functionality is preferable to failing to serve traffic.

Let’s look at an example of how this works. Our November 2025 outage was triggered by a failed rollout of our Bot Management detection machine learning classifier. Under our new procedures, if data were generated again that our system could not read, the system would refuse to use the updated configuration and instead use the old configuration. If the old configuration was not available for some reason, it would fail open to ensure customer production traffic continues to be served, which is a much better outcome than downtime.

As a result, if the same Bot Management change that caused the failure in November were to roll out now, the system would detect the failure in an early stage of the deployment, before it had affected anything more than a small percentage of traffic.

We have also begun further segmenting our system so that independent copies of services run for different cohorts of traffic. Cloudflare already takes advantage of these customer cohorts for blast radius mitigation with traffic management techniques today, and this additional process segmentation work provides a powerful reliability capability for us going forward.  

For example, the Workers runtime system is segmented into multiple independent services handling different cohorts of traffic, with one handling only traffic for our free customers. Changes are deployed to these segments based on customer cohorts, starting with free customers first. We’re also sending updates more quickly and frequently to the least critical segments, and at a slower pace to the most critical segments.

As a result, if a change were deployed to the Workers runtime system and it broke traffic, it would now only affect a small percentage of our free customers before being automatically detected and rolled back.

Sticking to the Workers runtime system as an example, in a seven-day period earlier this month, the deployment process was triggered more than 50 times. You can see how each happens in “waves” as the change propagates to the edge, often in parallel to the following and prior releases:


We’re working on extending this pattern of deployment to many more of our systems in the future.

Revised “break glass” and incident management procedures

What it means for you: If an incident does occur, we have the tools and teams to communicate more clearly and resolve it faster, minimizing downtime.

Cloudflare runs on Cloudflare. We use our own Zero Trust products to secure our infrastructure, but this creates a dependency: if a network-wide outage impacts these tools, we lose the very pathways we need to fix them. Before this Code Orange initiative, our “break glass” pathways were restricted to a handful of people and offered limited tool access. We needed these tools and pathways to be more broadly available during an outage.

To solve this, we conducted a comprehensive audit of the tools essential for system visibility, debugging, and production changes. We ultimately developed backup authorization pathways for 18 key services, supported by new emergency scripts and proxies.

Throughout the Code Orange program, we moved from theory to practice. After small-team exercises, we conducted an engineering-wide drill on April 7, 2026, involving more than 200 team members. While automation keeps these pathways functional, drills like these ensure our engineers have the muscle memory to use them under pressure.

This effort also focused on the flow of information. When internal visibility is disrupted, our incident response slows down, and our ability to communicate with the outside world suffers. Historically, technical observations from the heat of the moment didn’t always translate into clear updates for our customers.

To bridge this gap, we established a dedicated communications team to work in lockstep with incident responders during major events. Just as our engineers practiced their “break glass” procedures, this team used the Code Orange program to drill on streamlining the cadence and clarity of customer updates. By ensuring we have both the tools to see and the structure to speak, we can resolve incidents faster and keep our customers better informed.

We have codified our improvements

What it means for you: We will remember the learnings from our incidents and have codified the resolutions. Our network will only become more resilient.

To avoid drift and reintroducing regressions to the work done as part of Code Orange over time, the team has built an internal Codex that solidifies all our guidelines in clear and concise rules.

The Codex is now mandatory for all engineering and product teams, and has become a central part of Cloudflare internal procedures. Its rules are enforced via AI code reviews that automatically highlight any instance that might diverge from the guidelines, requiring additional manual reviews be performed. This is applied without exception to our entire codebase. The goal is simple: Build institutional memory that enforces itself.

The November and December outages shared a common failure mode: code that assumed inputs would always be valid, with no graceful degradation when that assumption broke. A Rust service called .unwrap() instead of handling an error; Lua code indexed an object that didn’t exist. Both patterns are preventable if the lessons are captured and enforced.

The Codex is part of our answer. It’s a living repository of engineering standards written by domain experts through our Request For Comments (RFC) process, then distilled into actionable rules. Best practices that previously lived in the heads of senior engineers, or were discovered only after an incident, now become shared knowledge accessible to everyone. Each rule follows a simple format: “If you need X, use Y” with a link to the RFC that explains why.

For example, one RFC now states: “Do not use .unwrap() outside of tests and `build.rs.`” Another captures a broader principle: “Services MUST validate that upstream dependencies are in an expected state before processing.”

Had these rules been enforced earlier, the November and December outages would have been rejected merge requests instead of global incidents.

Rules without enforcement are suggestions. The Codex integrates with AI-powered agents at every stage of the software development lifecycle, from design review through deployment to incident analysis. This shifts enforcement left, from “global outage” to “rejected merge request.” The blast radius of a violation shrinks from millions of affected requests to a single developer getting actionable feedback before their code ever reaches production.

The Codex is a living document and will be continuously improved over time. Domain experts write RFCs to codify best practices. Incidents surface gaps that become new RFCs. Every approved RFC generates Codex rules. Those rules feed the agents that review the next merge request. It’s a flywheel: expertise becomes standards, standards become enforcement, enforcement raises the floor for everyone.

It’s not just about code: communication is key

What it means for you: Transparency is important to us. If something goes wrong, we’re committed to keeping you updated every step of the way so you can stay focused on what matters to you.

The global outages have made us review core processes and cultural approaches even beyond engineering and product development. As part of the broader Code Orange initiatives, we have introduced additional service level objectives (SLOs) to all our services, enforced a global changelog, onboarded all teams to our maintenance coordination system, and improved transparency across the company on our incident “prevents” ticket backlog. 

We have also strengthened the way we communicate to our customers during an outage. Our goal is to alert you to an issue the moment we confirm it, before you even notice a problem. By the time you notice a lag or an error, our aim is to have an update already waiting in your notifications.

During an active incident, we now provide updates at predictable intervals (e.g., every 30 or 60 minutes), even if the update is simply, “We are still testing the fix; no new changes yet.” This allows you to plan your day rather than constantly refreshing a status page.

Our job isn’t done when the status returns to normal. We provide detailed post-mortems explaining what happened, why it happened, and the specific structural changes we are making to ensure it doesn’t happen again.

This initiative is complete. But our work on resiliency is never done.

We take the incidents very seriously and adopted a shared ownership across the entire Cloudflare organization by asking every team: What could have been done better? This guided the work that we carried out over the last two quarters.

While this work is never truly done, we are confident that we are in a much better position and Cloudflare is now much stronger because of it.

Cloudflare service outage June 12, 2025

Post Syndicated from Jeremy Hartman original https://blog.cloudflare.com/cloudflare-service-outage-june-12-2025/

On June 12, 2025, Cloudflare suffered a significant service outage that affected a large set of our critical services, including Workers KV, WARP, Access, Gateway, Images, Stream, Workers AI, Turnstile and Challenges, AutoRAG, Zaraz, and parts of the Cloudflare Dashboard.

This outage lasted 2 hours and 28 minutes, and globally impacted all Cloudflare customers using the affected services. The cause of this outage was due to a failure in the underlying storage infrastructure used by our Workers KV service, which is a critical dependency for many Cloudflare products and relied upon for configuration, authentication and asset delivery across the affected services. Part of this infrastructure is backed by a third-party cloud provider, which experienced an outage today and directly impacted availability of our KV service.

We’re deeply sorry for this outage: this was a failure on our part, and while the proximate cause (or trigger) for this outage was a third-party vendor failure, we are ultimately responsible for our chosen dependencies and how we choose to architect around them.

This was not the result of an attack or other security event. No data was lost as a result of this incident. Cloudflare Magic Transit and Magic WAN, DNS, cache, proxy, WAF and related services were not directly impacted by this incident.

What was impacted?

As a rule, Cloudflare designs and builds our services on our own platform building blocks, and as such many of Cloudflare’s products are built to rely on the Workers KV service. 

The following table details the impacted services, including the user-facing impact, operation failures, and increases in error rates observed:

Product/Service

Impact

Workers KV

Workers KV saw 90.22% of requests failing: any key-value pair not cached and that required to retrieve the value from Workers KV’s origin storage backends resulted in failed requests with response code 503 or 500. 

The remaining requests were successfully served from Workers KV’s cache (status code 200 and 404) or returned errors within our expected limits and/or error budget.

This did not impact data stored in Workers KV.

Access

Access uses Workers KV to store application and policy configuration along with user identity information.

During the incident Access failed 100% of identity based logins for all application types including Self-Hosted, SaaS and Infrastructure. User Identity information was unavailable to other services like WARP and Gateway during this incident. Access is designed to fail closed when it cannot successfully fetch policy configuration or a user’s identity. 

Active Infrastructure Application SSH sessions with command logging enabled failed to save logs due to a Workers KV dependency. 

Access’ System for Cross Domain Identity (SCIM) service was also impacted due to its reliance on Workers KV and Durable Objects (which depended on KV) to store user information. During this incident, user identities were not updated due to Workers KV updates failures. These failures would result in a 500 returned to identity providers. Some providers may require a manual re-synchronization but most customers would have seen immediate service restoration once Access’ SCIM service was restored due to retry logic by the identity provider.

Service authentication based logins (e.g. service token, Mutual TLS, and IP-based policies) and Bypass policies were unaffected. No Access policy edits or changes were lost during this time.

Gateway

This incident did not affect most Gateway DNS queries, including those over IPv4, IPv6, DNS over TLS (DoT), and DNS over HTTPS (DoH).

However, there were two exceptions:

DoH queries with identity-based rules failed. This happened because Gateway couldn’t retrieve the required user’s identity information.

Authenticated DoH was disrupted for some users. Users with active sessions with valid authentication tokens were unaffected, but those needing to start new sessions or refresh authentication tokens could not.

Users of Gateway proxy, egress, and TLS decryption were unable to connect, register, proxy, or log traffic.

This was due to our reliance on Workers KV to retrieve up-to-date identity and device posture information. Each of these actions requires a call to Workers KV, and when unavailable, Gateway is designed to fail closed to prevent traffic from bypassing customer-configured rules.

WARP

The WARP client was impacted due to core dependencies on Access and Workers KV, which is required for device registration and authentication. As a result, no new clients were able to connect or sign up during the incident.

Existing WARP client users sessions that were routed through the Gateway proxy experienced disruptions, as Gateway was unable to perform its required policy evaluations.

Additionally, the WARP emergency disconnect override was rendered unavailable because of a failure in its underlying dependency, Workers KV.

Consumer WARP saw a similar sporadic impact as the Zero Trust version.

Dashboard

Dashboard user logins and most of the existing dashboard sessions were unavailable. This was due to an outage affecting Turnstile, DO, KV, and Access. The specific causes for login failures were:

Standard Logins (User/Password): Failed due to Turnstile unavailability.

Sign-in with Google (OIDC) Logins: Failed due to a KV dependency issue.

SSO Logins: Failed due to a full dependency on Access.

The Cloudflare v4 API was not impacted during this incident.

Challenges and Turnstile

The Challenge platform that powers Cloudflare Challenges and Turnstile saw a high rate of failure and timeout for siteverify API requests during the incident window due to its dependencies on Workers KV and Durable Objects.

We have kill switches in place to disable these calls in case of incidents and outages such as this. We activated these kill switches as a mitigation so that eyeballs are not blocked from proceeding. Notably, while these kill switches were active, Turnstile’s siteverify API (the API that validates issued tokens) could redeem valid tokens multiple times, potentially allowing for attacks where a bad actor might try to use a previously valid token to bypass. 

There was no impact to Turnstile’s ability to detect bots. A bot attempting to solve a challenge would still have failed the challenge and thus, not received a token. 

Browser Isolation

Existing Browser Isolation sessions via Link-based isolation were impacted due to a reliance on Gateway for policy evaluation.

New link-based Browser Isolation sessions could not be initiated due to a dependency on Cloudflare Access. All Gateway-initiated isolation sessions failed due its Gateway dependency.

Images

Uploads to Cloudflare Images were impacted during the incident window, with a 100% failure rate at the peak of the incident. 

Overall image delivery dipped to around 97% success rate. Image Transformations were not significantly impacted, and Polish was not impacted.

Stream

Stream’s error rate exceeded 90% during the incident window as video playlists were unable to be served. Stream Live observed a 100% error rate.

Video uploads were not impacted.

Realtime

The Realtime TURN (Traversal Using Relays around NAT) service uses KV and was heavily impacted. Error rates were near 100% for the duration of the incident window.

The Realtime SFU service (Selective Forwarding Unit) was unable to create new sessions, although existing connections were maintained. This caused a reduction to 20% of normal traffic during the impact window. 

Workers AI

All inference requests to Workers AI failed for the duration of the incident. Workers AI depends on Workers KV for distributing configuration and routing information for AI requests globally.

Pages & Workers Assets

Static assets served by Cloudflare Pages and Workers Assets (such as HTML, JavaScript, CSS, images, etc) are stored in Workers KV, cached, and retrieved at request time. Workers Assets saw an average error rate increase of around 0.06% of total requests during this time. 

During the incident window, Pages error rate peaked to ~100% and all Pages builds could not complete. 

AutoRAG

AutoRAG relies on Workers AI models for both document conversion and generating vector embeddings during indexing, as well as LLM models for querying and search. AutoRAG was unavailable during the incident window because of the Workers AI dependency.

Durable Objects

SQLite-backed Durable Objects share the same underlying storage infrastructure as Workers KV. The average error rate during the incident window peaked at 22%, and dropped to 2% as services started to recover.

Durable Object namespaces using the legacy key-value storage were not impacted.

D1

D1 databases share the same underlying storage infrastructure as Workers KV and Durable Objects.

Similar to Durable Objects, the average error rate during the incident window peaked at 22%, and dropped to 2% as services started to recover.

Queues & Event Notifications

Queues message operations including–pushing and consuming–were unavailable during the incident window.

Queues uses KV to map each Queue to underlying Durable Objects that contain queued messages.

Event Notifications use Queues as their underlying delivery mechanism.

AI Gateway

AI Gateway is built on top of Workers and relies on Workers KV for client and internal configurations. During the incident window, AI Gateway saw error rates peak at 97% of requests until dependencies recovered.

CDN

Automated traffic management infrastructure was operational but acted with reduced efficacy during the impact period. In particular, registration requests from Zero Trust clients increased substantially as a result of the outage.

The increase in requests imposed additional load in several Cloudflare locations, triggering response from automated traffic management. In response to these conditions, systems rerouted incoming CDN traffic to nearby locations, reducing impact to customers. There was a portion of traffic that was not rerouted as expected and is under investigation. CDN requests impacted by this issue would experience elevated latency, HTTP 499 errors, and / or HTTP 503 errors. Impacted Cloudflare service areas included São Paulo, Philadelphia, Atlanta, and Raleigh.

Workers / Workers for Platforms

Workers and Workers for Platforms rely on a third party service for uploads. During the incident window, Workers saw an overall error rate peak to ~2% of total requests. Workers for Platforms saw an overall error rate peak to ~10% of total requests during the same time period. 

Workers Builds (CI/CD)
 

Starting at 18:03 UTC Workers builds could not receive new source code management push events due to Access being down.

100% of new Workers Builds failed during the incident window.

Browser Rendering

Browser Rendering depends on Browser Isolation for browser instance infrastructure.

Requests to both the REST API and via the Workers Browser Binding were 100% impacted during the incident window.

Zaraz

100% of requests were impacted during the incident window. Zaraz relies on Workers KV configs for websites when handling eyeball traffic. Due to the same dependency, attempts to save updates to Zaraz configs were unsuccessful during this period, but our monitoring shows that only a single user was affected.

Background

Workers KV is built as what we call a “coreless” service which means there should be no single point of failure as the service runs independently in each of our locations worldwide. However, Workers KV today relies on a central data store to provide a source of truth for data. A failure of that store caused a complete outage for cold reads and writes to the KV namespaces used by services across Cloudflare.

Workers KV is in the process of being transitioned to significantly more resilient infrastructure for its central store: regrettably, we had a gap in coverage which was exposed during this incident. Workers KV removed a storage provider as we worked to re-architect KV’s backend, including migrating it to Cloudflare R2, to prevent data consistency issues (caused by the original data syncing architecture), and to improve support for data residency requirements.

One of our principles is to build Cloudflare services on our own platform as much as possible, and Workers KV is no exception. Many of our internal and external services rely heavily on Workers KV, which under normal circumstances helps us deliver the most robust services possible, instead of service teams attempting to build their own storage services. In this case, the cascading impact from the failure from Workers KV exacerbated the issue and significantly broadened the blast radius. 

Incident timeline and impact

The incident timeline, including the initial impact, investigation, root cause, and remediation, are detailed below. 


Workers KV error rates to storage infrastructure. 91% of requests to KV failed during the incident window.


Cloudflare Access percentage of successful requests. Cloudflare Access relies directly on Workers KV and serves as a good proxy to measure Workers KV availability over time.

All timestamps referenced are in Coordinated Universal Time (UTC).

Time

Event

2025-06-12 17:52

INCIDENT START
Cloudflare WARP team begins to see registrations of new devices fail and begin to investigate these failures and declares an incident.

2025-06-12 18:05

Cloudflare Access team received an alert due to a rapid increase in error rates.

Service Level Objectives for multiple services drop below targets and trigger alerts across those teams.

2025-06-12 18:06

Multiple service-specific incidents are combined into a single incident as we identify a shared cause (Workers KV unavailability). Incident priority upgraded to P1.

2025-06-12 18:21

Incident priority upgraded to P0 from P1 as severity of impact becomes clear.

2025-06-12 18:43

Cloudflare Access begins exploring options to remove Workers KV dependency by migrating to a different backing datastore with the Workers KV engineering team. This was proactive in the event the storage infrastructure continued to be down.

2025-06-12 19:09

Zero Trust Gateway began working to remove dependencies on Workers KV by gracefully degrading rules that referenced Identity or Device Posture state.

2025-06-12 19:32

Access and Device Posture force drop identity and device posture requests to shed load on Workers KV until third-party service comes back online.

2025-06-12 19:45

Cloudflare teams continue to work on a path to deploying a Workers KV release against an alternative backing datastore and having critical services write configuration data to that store.

2025-06-12 20:23

Services begin to recover as storage infrastructure begins to recover. We continue to see a non-negligible error rate and infrastructure rate limits due to the influx of services repopulating caches.

2025-06-12 20:25

Access and Device Posture restore calling Workers KV as third-party service is restored.

2025-06-12 20:28

IMPACT END 
Service Level Objectives return to pre-incident level. Cloudflare teams continue to monitor systems to ensure services do not degrade as dependent systems recover.

INCIDENT END
Cloudflare team see all affected services return to normal function. Service level objective alerts are recovered.

Remediation and follow-up steps

We’re taking immediate steps to improve the resiliency of services that depend on Workers KV and our storage infrastructure. This includes existing planned work that we are accelerating as a result of this incident.

This encompasses several workstreams, including efforts to avoid singular dependencies on storage infrastructure we do not own, improving the ability for us to recover critical services (including Access, Gateway and WARP) 

Specifically:

  • (Actively in-flight): Bringing forward our work to improve the redundancy within Workers KV’s storage infrastructure, removing the dependency on any single provider. During the incident window we began work to cut over and backfill critical KV namespaces to our own infrastructure, in the event the incident continued.

  • (Actively in-flight): Short-term blast radius remediations for individual products that were impacted by this incident so that each product becomes resilient to any loss of service caused by any single point of failure, including third party dependencies..

  • (Actively in-flight): Implementing tooling that allows us to progressively re-enable namespaces during storage infrastructure incidents. This will allow us to ensure that key dependencies, including Access and WARP, are able to come up without risking a denial-of-service against our own infrastructure as caches are repopulated.

This list is not exhaustive: our teams continue to revisit design decisions and assess the infrastructure changes we need to make in both the near (immediate) term and long term to mitigate the incidents like this going forward.

This was a serious outage, and we understand that organizations and institutions that are large and small depend on us to protect and/or run their websites, applications, zero trust and network infrastructure.  Again we are deeply sorry for the impact and are working diligently to improve our service resiliency. 

How Cloudflare erroneously throttled a customer’s web traffic

Post Syndicated from Jeremy Hartman original https://blog.cloudflare.com/how-cloudflare-erroneously-throttled-a-customers-web-traffic/

How Cloudflare erroneously throttled a customer’s web traffic

How Cloudflare erroneously throttled a customer’s web traffic

Over the years when Cloudflare has had an outage that affected our customers we have very quickly blogged about what happened, why, and what we are doing to address the causes of the outage. Today’s post is a little different. It’s about a single customer’s website not working correctly because of incorrect action taken by Cloudflare.

Although the customer was not in any way banned from Cloudflare, or lost access to their account, their website didn’t work. And it didn’t work because Cloudflare applied a bandwidth throttle between us and their origin server. The effect was that the website was unusable.

Because of this unusual throttle there was some internal confusion for our customer support team about what had happened. They, incorrectly, believed that the customer had been limited because of a breach of section 2.8 of our Self-Serve Subscription Agreement which prohibits use of our self-service CDN to serve excessive non-HTML content, such as images and video, without a paid plan that includes those services (this is, for example, designed to prevent someone building an image-hosting service on Cloudflare and consuming a huge amount of bandwidth; for that sort of use case we have paid image and video plans).

However, this customer wasn’t breaking section 2.8, and they were both a paying customer and a paying customer of Cloudflare Workers through which the throttled traffic was passing. This throttle should not have happened. In addition, there is and was no need for the customer to upgrade to some other plan level.

This incident has set off a number of workstreams inside Cloudflare to ensure better communication between teams, prevent such an incident happening, and to ensure that communications between Cloudflare and our customers are much clearer.

Before we explain our own mistake and how it came to be, we’d like to apologize to the customer. We realize the serious impact this had, and how we fell short of expectations. In this blog post, we want to explain what happened, and more importantly what we’re going to change to make sure it does not happen again.

Background

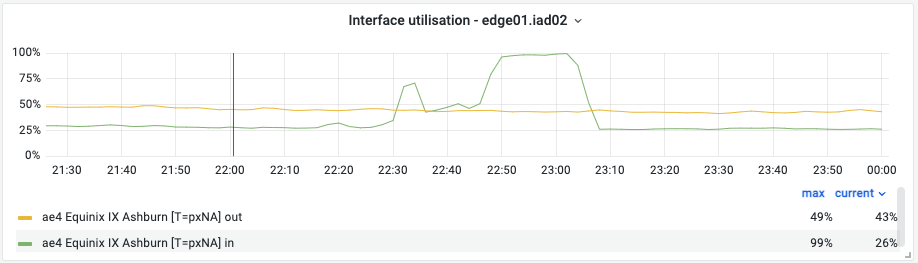
On February 2, an on-call network engineer received an alert for a congesting interface with Equinix IX in our Ashburn data center. While this is not an unusual alert, this one stood for two reasons. First, it was the second day in a row that it happened, and second, the congestion was due to a sudden and extreme spike of traffic.

How Cloudflare erroneously throttled a customer’s web traffic

The engineer in charge identified the customer’s domain as being responsible for this sudden spike of traffic between Cloudflare and their origin network, a storage provider. Because this congestion happens on a physical interface connected to external peers, there was an immediate impact to many of our customers and peers. A port congestion like this one typically incurs packet loss, slow throughput and higher than usual latency. While we have automatic mitigation in place for congesting interfaces, in this case the mitigation was unable to resolve the impact completely.

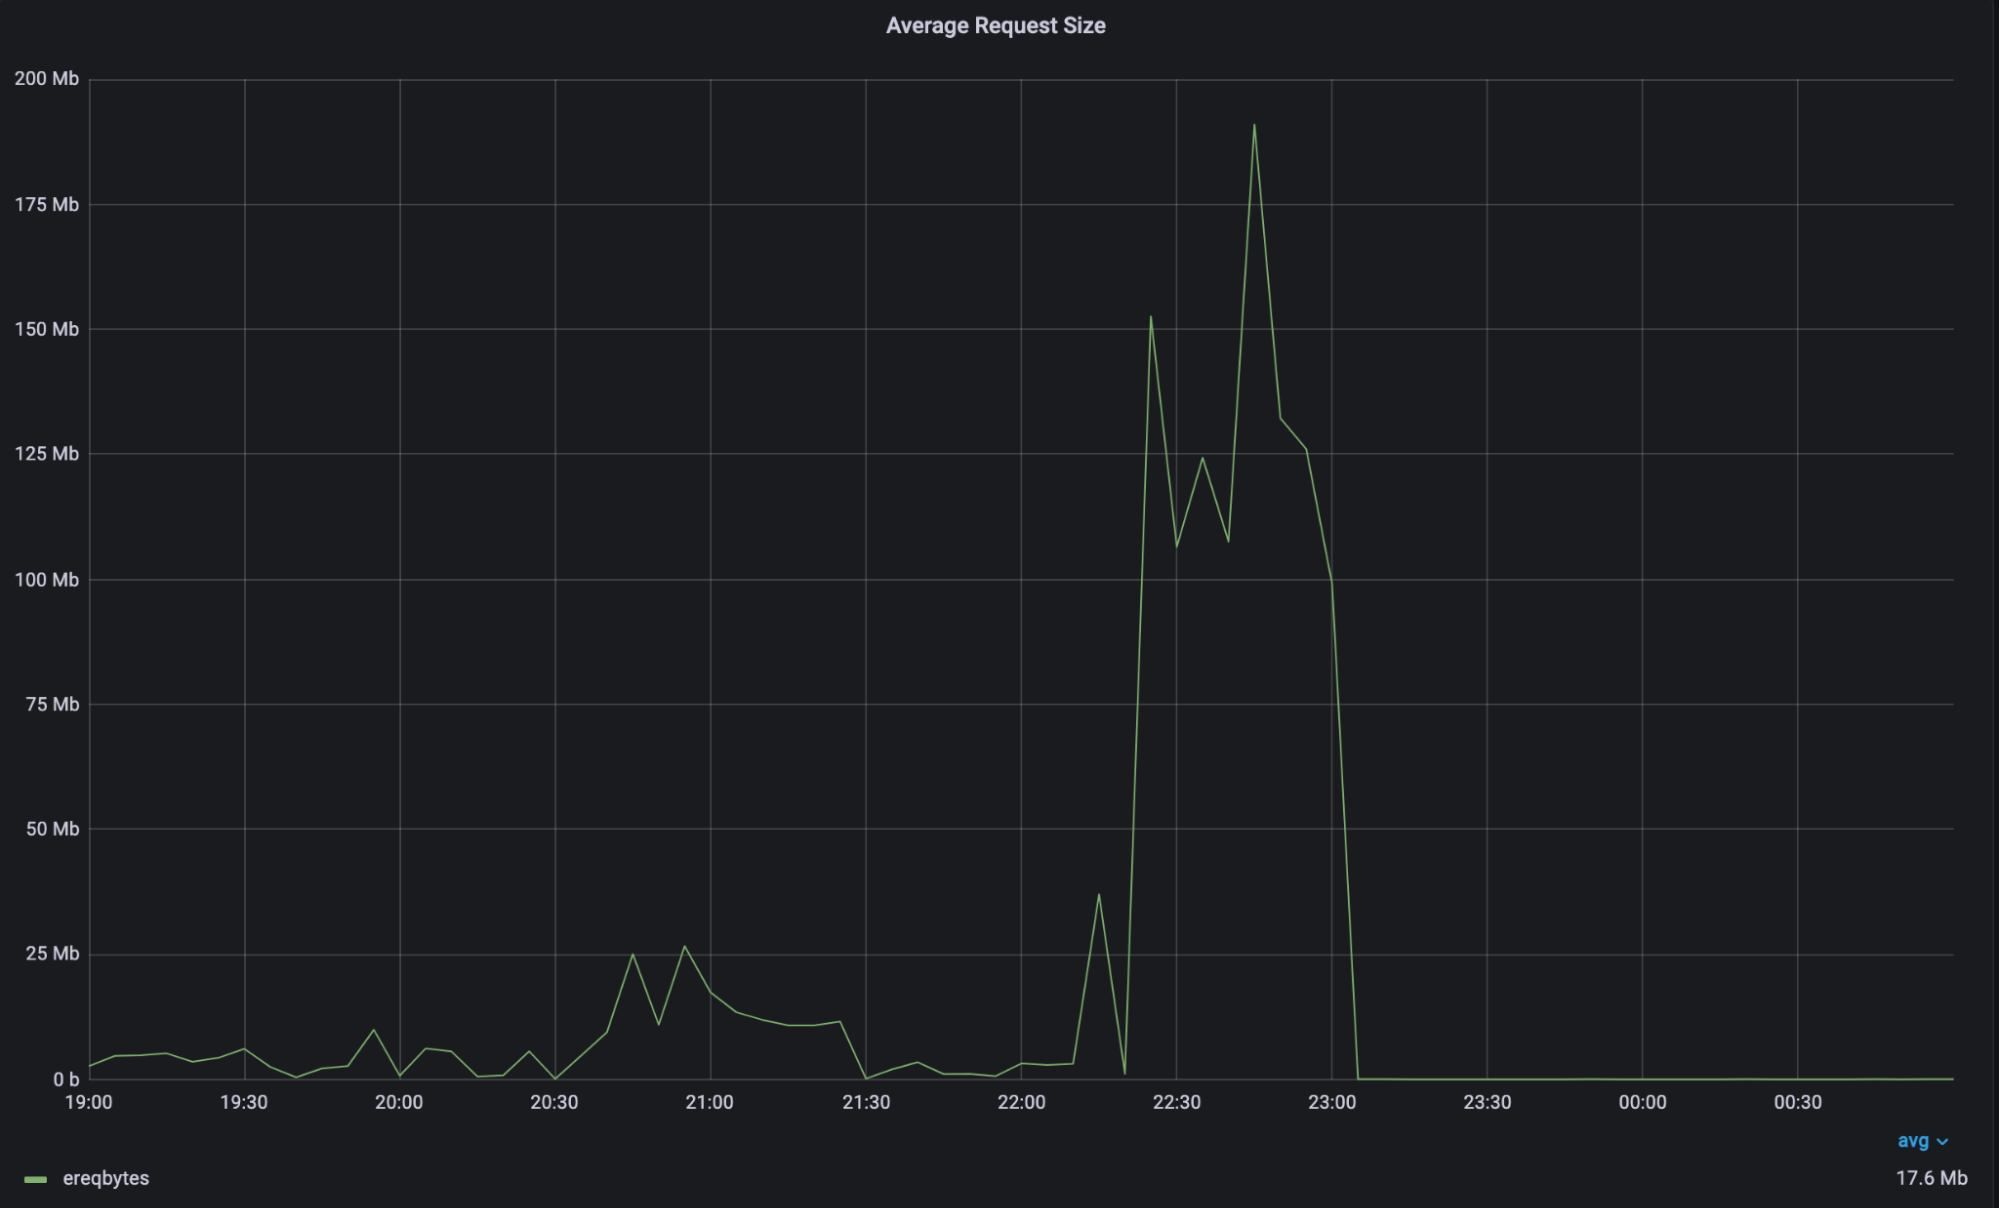
The traffic from this customer went suddenly from an average of 1,500 requests per second, and a 0.5 MB payload per request, to 3,000 requests per second (2x) and more than 12 MB payload per request (25x).

How Cloudflare erroneously throttled a customer’s web traffic

The congestion happened between Cloudflare and the origin network. Caching did not happen because the requests were all unique URLs going to the origin, and therefore we had no ability to serve from cache.

A Cloudflare engineer decided to apply a throttling mechanism to prevent the zone from pulling so much traffic from their origin. Let’s be very clear on this action: Cloudflare does not have an established process to throttle customers that consume large amounts of bandwidth, and does not intend to have one. This remediation was a mistake, it was not sanctioned, and we deeply regret it.

We lifted the throttle through internal escalation 12 hours and 53 minutes after having set it up.

What’s next

To make sure a similar incident does not happen, we are establishing clear rules to mitigate issues like this one. Any action taken against a customer domain, paying or not, will require multiple levels of approval and clear communication to the customer. Our tooling will be improved to reflect this. We have many ways of traffic shaping in situations where a huge spike of traffic affects a link and could have applied a different mitigation in this instance.

We are in the process of rewriting our terms of service to better reflect the type of services that our customers deliver on our platform today. We are also committed to explaining to our users in plain language what is permitted under self-service plans. As a developer-first company with transparency as one of its core principles, we know we can do better here. We will follow up with a blog post dedicated to these changes later.

Once again, we apologize to the customer for this action and for the confusion it created for other Cloudflare customers.

Incorrect proxying of 24 hostnames on January 24, 2022

Post Syndicated from Jeremy Hartman original https://blog.cloudflare.com/incorrect-proxying-of-24-hostnames-on-january-24-2022/

Incorrect proxying of 24 hostnames on January 24, 2022

On January 24, 2022, as a result of an internal Cloudflare product migration, 24 hostnames (including www.cloudflare.com) that were actively proxied through the Cloudflare global network were mistakenly redirected to the wrong origin. During this incident, traffic destined for these hostnames was passed through to the clickfunnels.com origin and may have resulted in a clickfunnels.com page being displayed instead of the intended website. This was our doing and clickfunnels.com was unaware of our error until traffic started to reach their origin.

API calls or other expected responses to and from these hostnames may not have responded properly, or may have failed completely. For example, if you were making an API call to api.example.com, and api.example.com was an impacted hostname, you likely would not have received the response you would have expected.

Here is what happened:

At 2022-01-24 22:24 UTC we started a migration of hundreds of thousands of custom hostnames to the Cloudflare for SaaS product. Cloudflare for SaaS allows SaaS providers to manage their customers’ websites and SSL certificates at scale – more information is available here. This migration was intended to be completely seamless, with the outcome being enhanced features and security for our customers. The migration process was designed to read the custom hostname configuration from a database and migrate it from SaaS v1 (the old system) to SaaS v2 (the current version) automatically.

To better understand what happened next, it’s important to explain a bit more about how custom hostnames are configured.

First, Cloudflare for SaaS customers can configure any hostname; but before we will proxy traffic to them, they must prove (via DNS validation) that they actually are allowed to handle that hostname’s traffic.

When the Cloudflare for SaaS customer first configures the hostname, it is marked as pending until DNS validation has occurred. Pending hostnames are very common for Cloudflare for SaaS customers as the hostname gets provisioned, and then the SaaS provider will typically work with their customer to put in place the appropriate DNS validation that proves ownership.

Once a hostname passes DNS validation, it moves from a pending state to an active state and can be proxied. Except in one case: there’s a special check for whether the hostname is marked as blocked within Cloudflare’s system. A blocked hostname is one that can’t be activated without manual approval by our Trust & Safety team. Some scenarios that could lead to a hostname being blocked include when the hostname is a Cloudflare-owned property, a well known brand, or a hostname in need of additional review for a variety of reasons.

During this incident, a very small number of blocked hostnames were erroneously moved to the active state while migrating clickfunnels.com’s customers. Once that occurred, traffic destined for those previously blocked hostnames was then processed by a configuration belonging to clickfunnels.com, sending traffic to the clickfunnels.com’s origin. One of those hostnames was www.cloudflare.com. Note that it was www.cloudflare.com and not cloudflare.com, so subdomains like dash.cloudflare.com, api.cloudflare.com, cdnjs.cloudflare.com, and so on were unaffected by this problem.

As the migration process continued down the list of hostnames, additional traffic was re-routed to the clickfunnels.com origin. At 23:06 UTC www.cloudflare.com was affected. At 23:15 UTC an incident was declared internally. Since the first alert we received was for www.cloudflare.com, we started our investigation there. In the next 19 minutes, the team restored www.cloudflare.com to its correct origin, determined the breadth of the impact and the root cause of the incident, and began remediation for the remaining affected hostnames.

By 2022-01-25 00:13 UTC, all custom hostnames had been restored to their proper configuration and the incident was closed. We have contacted all the customers who were affected by this error. We have worked with ClickFunnels to delete logs of this event to ensure that no data erroneously sent to the clickfunnels.com’s origin is retained by them and are very grateful for their speedy assistance.

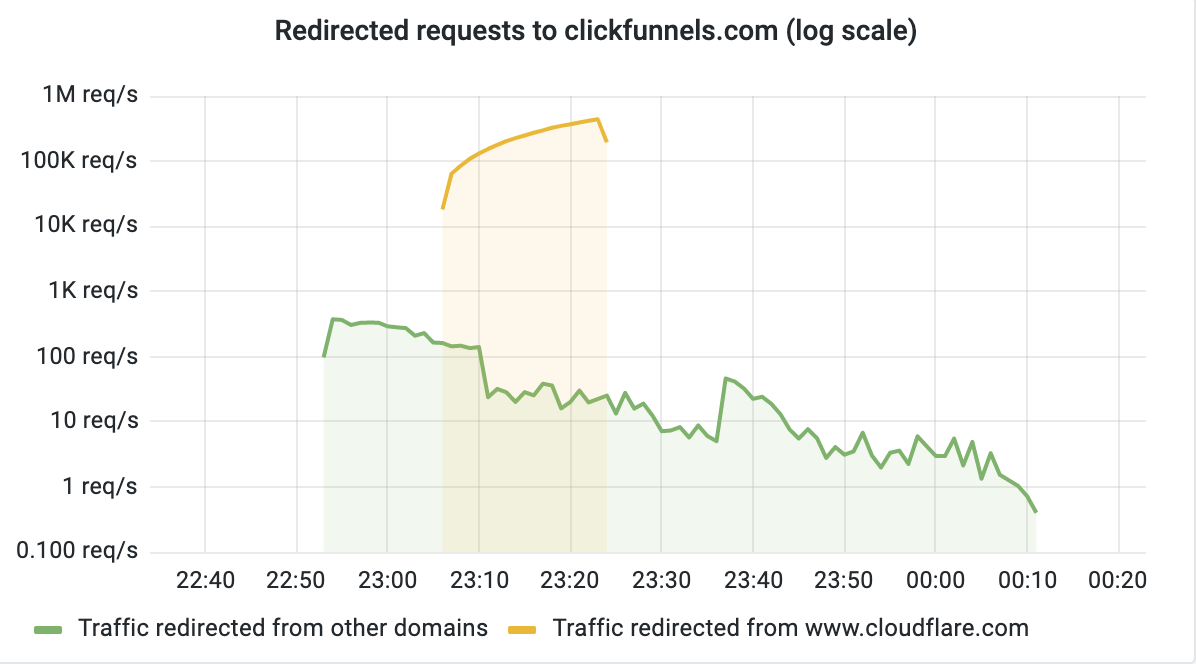
Here is a graph (on a log scale) of requests to clickfunnels.com during the event. Out of a total of 268,430,157 requests redirected, 268,220,296 (99.92%) were for www.cloudflare.com:

Incorrect proxying of 24 hostnames on January 24, 2022

At Cloudflare, we take these types of incidents very seriously, dedicating massive amounts of resources in preventative action and in follow-up engineering. In this case, there are both procedural and technical follow-ups to prevent reoccurrence. Here are our next steps:

  • No more blocked hostname overrides. All blocked hostname changes will route through our verification pipeline as part of the migration process.
  • All migrations will require explicit validation and approval from SaaS customers for a blocked hostname to be considered for activation.
  • Additional monitoring will be added to the hostnames being migrated to spot potential erroneous traffic patterns and alert the migration team.
  • Additional monitoring added for www.cloudflare.com.
  • Stage hostname activations on non-production elements prior to promoting to production will enable the ability to verify the new hostname state is expected. This will allow us to catch issues before they hit production traffic.

Conclusion

This event exposed previously unknown gaps in our process and technology that directly impacted our customers. We are truly sorry for the disruption to our customers and any potential visitor to the impacted properties. Our commitment is to provide fully reliable and secure products, and we will continue to make every effort possible to deliver just that for our customers and partners.