All posts by Salman Ahmed

Network connectivity patterns for the next generation of Amazon OpenSearch Serverless

Post Syndicated from Salman Ahmed original https://aws.amazon.com/blogs/big-data/network-connectivity-patterns-for-the-next-generation-of-amazon-opensearch-serverless/

Network connectivity patterns for private access to Amazon OpenSearch Serverless used to require considerable setup. You had to create virtual private cloud (VPC) endpoints in every consumer VPC and configure Amazon Route 53 Profiles for cross-account DNS. You also had to maintain custom private hosted zones with CNAME records and deploy resolver inbound endpoints for on-premises connectivity. The next generation of OpenSearch Serverless changes this. It uses standard AWS PrivateLink interface endpoints with native private DNS support. Connectivity patterns that previously required multi-step DNS orchestration now work with the same endpoint mechanics you already use for other AWS services.

Collections use resource-based endpoints on the on.aws domain in two formats. The per-collection endpoint (<collectionId>.aoss.<region>.on.aws) reaches a single collection, and the hostname itself identifies which collection you want, so no additional routing information is needed. The per-account Regional endpoint (<accountId>.aoss.<region>.on.aws) reaches any collection in your account through one hostname. Because the hostname alone does not identify a specific collection, you add the x-amz-aoss-collection-name header (or x-amz-aoss-collection-id) to each request to name the target collection. The AWS SDKs include this header automatically when they sign the request with Signature Version 4 (SigV4).

Both formats use standard AWS PrivateLink. You create the VPC endpoint from the Amazon Virtual Private Cloud (Amazon VPC) console or the Amazon Elastic Compute Cloud (Amazon EC2) CreateVpcEndpoint API, using the service name com.amazonaws.<region>.aoss-data. It is the same interface endpoint you create for any other AWS service.

In this post, each pattern shows the architecture, the DNS resolution flow, and the data traffic path. Patterns 1 through 8 operate within a single Region across one or more accounts, labeled Region A in the diagrams, so the repeated Region A boxes in a cross-account pattern are the same Region. Only Pattern 9 spans Regions, shown as Region A and Region B.

These patterns apply to the collection (data) endpoint only. When you create a collection, you also receive an OpenSearch UI endpoint. That endpoint uses a separate PrivateLink mechanism today, with its own VPC endpoint and access policy, and is on a path to move to the standard PrivateLink model. OpenSearch UI connectivity is out of scope for this post.

Prerequisites

DNS resolution

When you create a standard VPC endpoint for com.amazonaws.<region>.aoss-data with private DNS enabled, AWS creates a private hosted zone for *.aoss.<region>.on.aws and associates it with your VPC. This zone maps collection hostnames to the endpoint’s private elastic network interface (ENI) IP addresses. Your compute’s DNS query reaches the VPC’s Amazon Route 53 Resolver at VPC+2, which resolves the hostname to ENI IPs.

One endpoint serves every collection hostname in the Region. The following AWS CLI command creates that interface endpoint, and the --private-dns-enabled flag turns on the private DNS resolution described here.

aws ec2 create-vpc-endpoint \
  --vpc-id vpc-abc123 \
  --service-name com.amazonaws.us-east-1.aoss-data \
  --vpc-endpoint-type Interface \
  --subnet-ids subnet-111 subnet-222 \
  --security-group-ids sg-xxx \
  --private-dns-enabled

In Regions that support Federal Information Processing Standards (FIPS), the same endpoint also resolves *.aoss-fips.<region>.on.aws for FIPS-compliant access.

OpenSearch Serverless has no per-collection Dashboards endpoint. Use OpenSearch UI applications to explore and visualize collection data.

The diagrams in the following patterns use an Amazon EC2 instance to represent the compute client. Any compute in the VPC reaches a collection the same way, including EC2 instances, AWS Lambda functions attached to the VPC, and containers on Amazon Elastic Container Service (Amazon ECS) or Amazon Elastic Kubernetes Service (Amazon EKS). The connectivity, DNS resolution, and access policies are the same regardless of the compute type.

Pattern 1: Private access from a single VPC

Compute in a VPC needs private access to collections in the same account. The following diagram shows the architecture for private access from a single VPC.
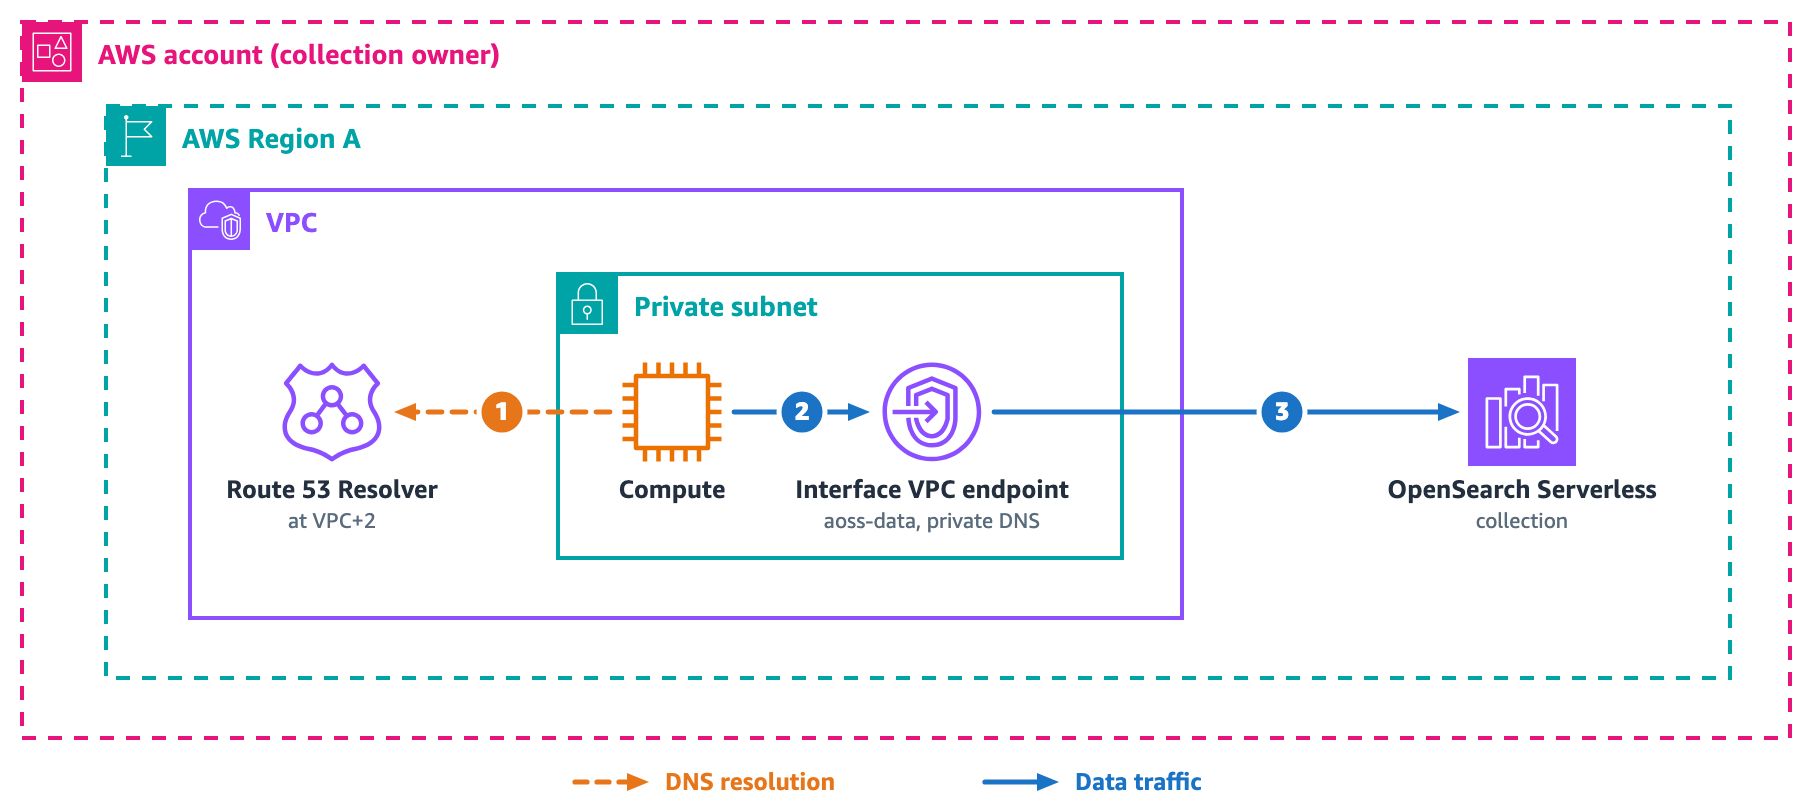
Compute in a single VPC reaches a collection through a VPC interface endpoint with private DNS enabled

Figure 1: Private access from a single VPC

Create a standard VPC endpoint in the VPC where your compute runs, then reference its ID in the collection’s network policy.

For the DNS resolution flow, (1) compute queries <collectionId>.aoss.<region>.on.aws, and the VPC Route 53 Resolver at VPC+2 returns the endpoint ENI IP addresses because private DNS is enabled on the endpoint.

For the data traffic path, (2) compute connects to the ENI, and (3) PrivateLink forwards the request to the service, which routes to the collection by hostname.

Pattern 2: Multiple VPCs in the same account

Several VPCs, split by environment, tier, or team, need private access to the same collections. The following diagram shows how each VPC uses its own endpoint to reach the same collections.
Three VPCs in one account, each with its own aoss-data interface endpoint reaching the same collections

Figure 2: Multiple VPCs in the same account

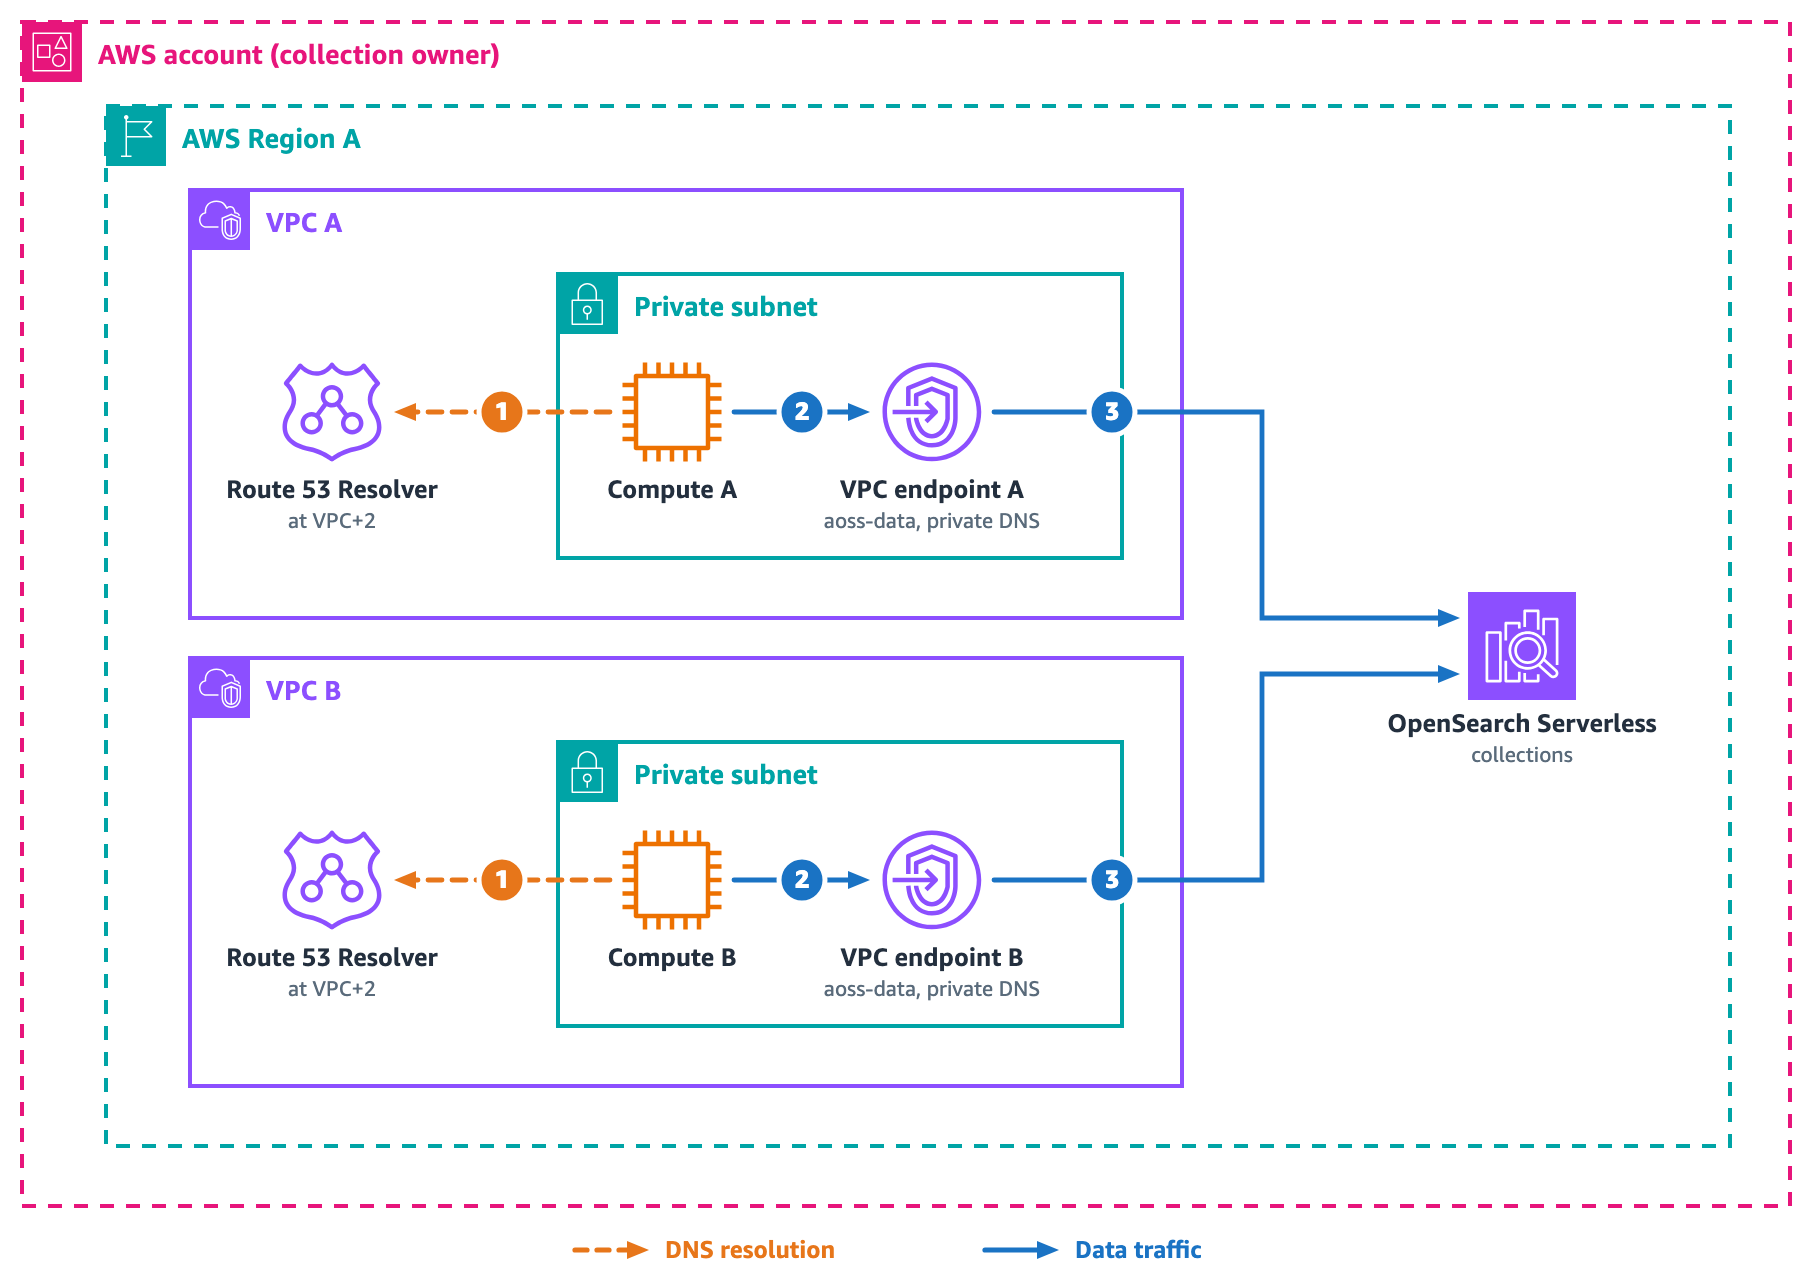
Each VPC needs exactly one aoss-data endpoint with private DNS enabled, and that single endpoint already reaches every collection in the Region. DNS resolves independently within each VPC, so there is no cross-VPC DNS dependency. Adding a new VPC takes two steps. Create the endpoint, then add its endpoint ID to the collection’s network policy. Do not create a second aoss-data endpoint with private DNS enabled in the same VPC. Both endpoints share the same private hosted zone, which causes a conflict and the creation fails.

For the DNS resolution flow, (1) compute in each VPC queries the collection hostname, and that VPC’s Route 53 Resolver at VPC+2 returns the endpoint ENI IP addresses because private DNS is enabled on the endpoint.

For the data traffic path, (2) compute connects to its local ENI, and (3) PrivateLink forwards the request to the service, which routes to the collection by hostname.

Pattern 3: On-premises access from a single account

On-premises clients reach collections over AWS Direct Connect or AWS Site-to-Site VPN, which connect to the VPC through AWS Transit Gateway or AWS Cloud WAN. The following diagram shows the DNS and data path for on-premises access.
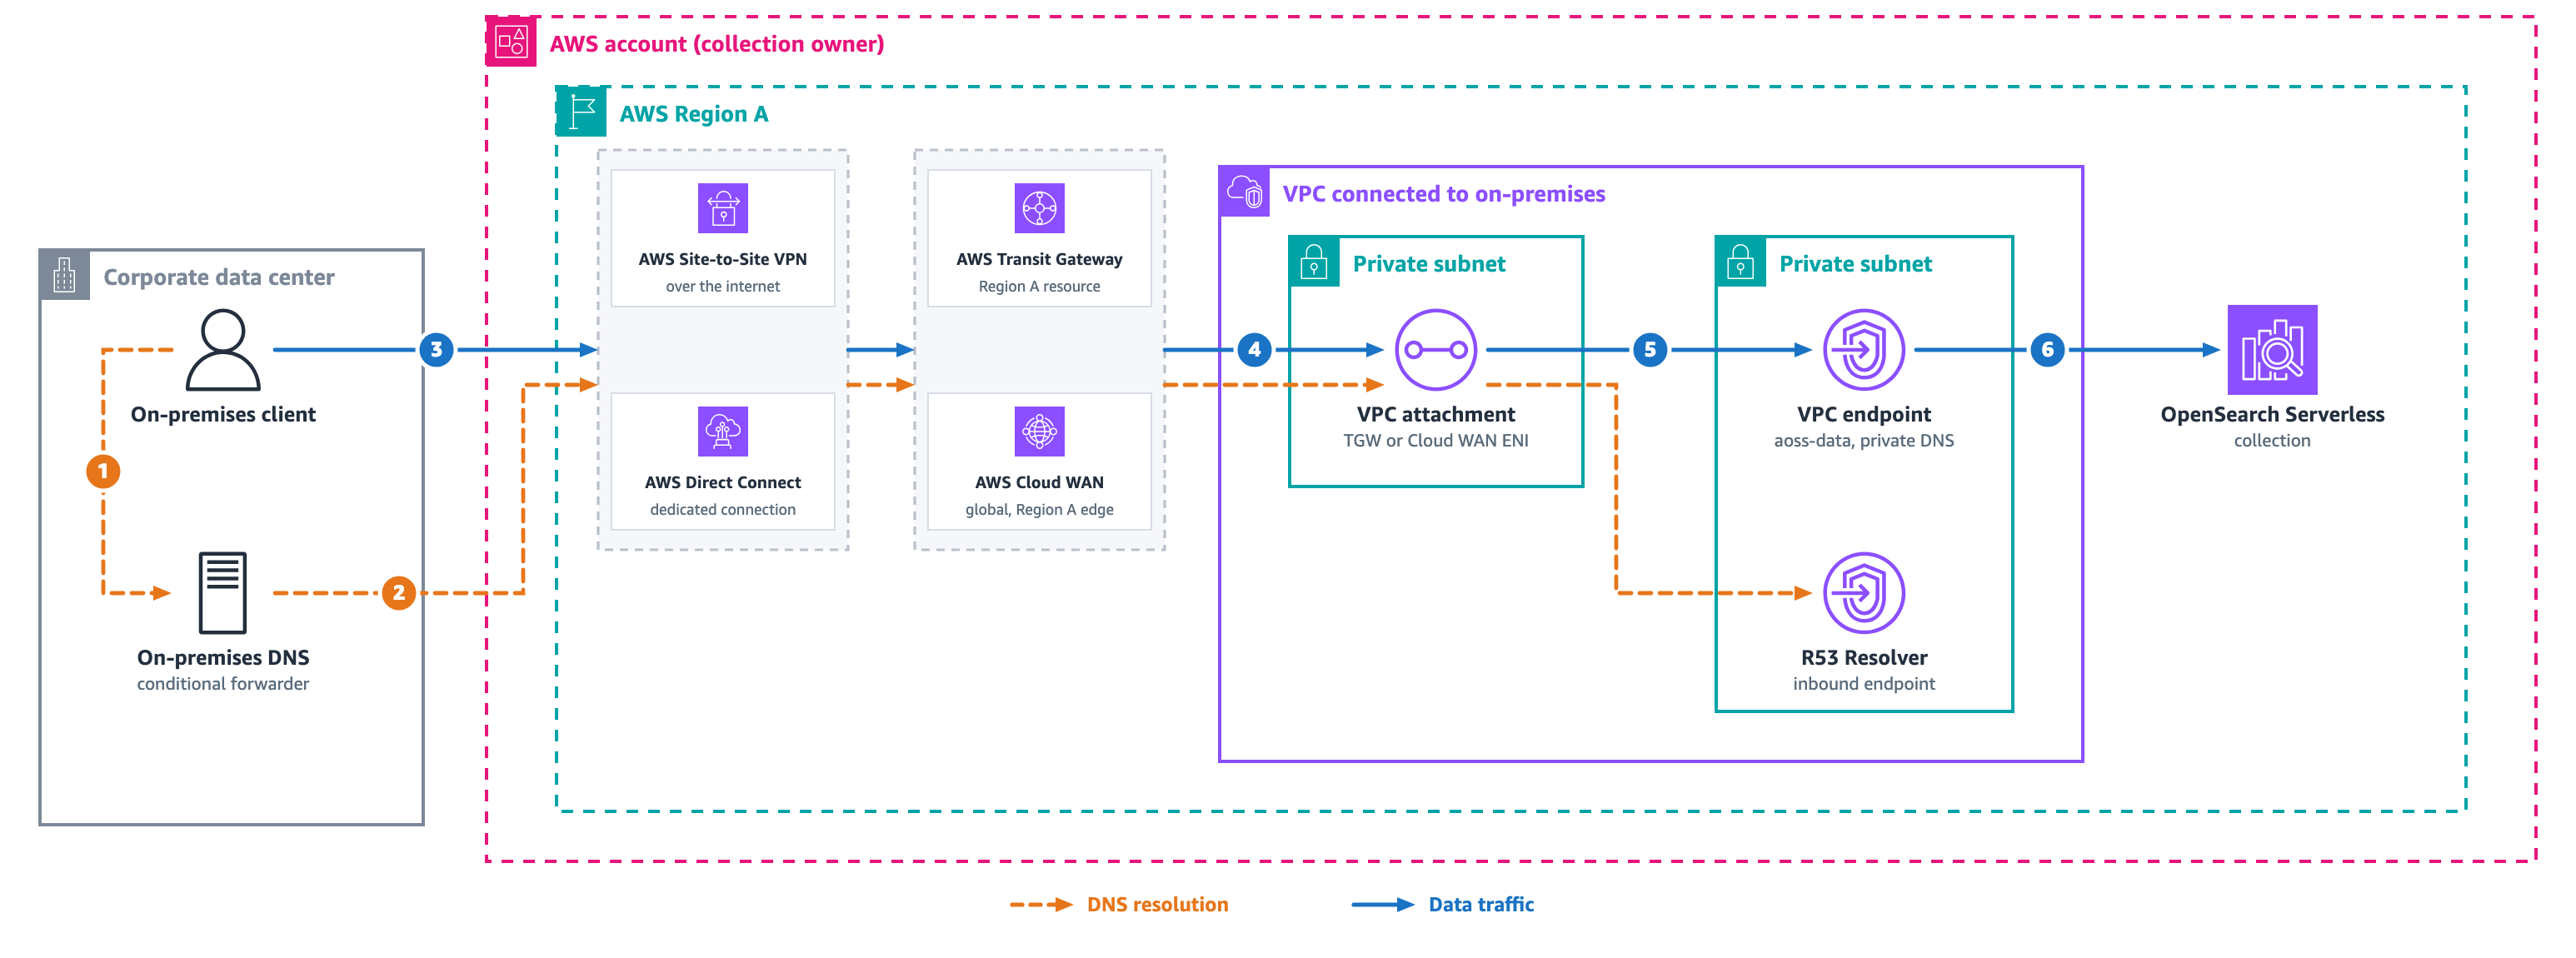
Figure 3: On-premises access from a single account

On-premises DNS servers sit outside the VPC and cannot resolve PrivateLink private DNS names directly. Place an Amazon Route 53 Resolver inbound endpoint in the VPC that holds the aoss-data VPC endpoint. On-premises DNS forwards queries for aoss.<region>.on.aws to that inbound endpoint. The inbound endpoint resolves them against the private hosted zone. The inbound endpoint’s security group must allow TCP/UDP port 53 from your on-premises resolver ranges.

For the DNS resolution flow, (1) the client queries the on-premises resolver. (2) The on-premises conditional forwarder for *.aoss.<region>.on.aws sends the query over Direct Connect or VPN, through Transit Gateway or Cloud WAN, to the inbound endpoint. The inbound endpoint uses the VPC Route 53 Resolver to return the endpoint’s private ENI IPs.

For the data traffic path, (3) the client sends an HTTPS request with the Transport Layer Security (TLS) Server Name Indication (SNI) header set to the collection hostname, over Direct Connect or VPN through Transit Gateway or Cloud WAN. (4) Traffic crosses the VPC’s attachment ENI, (5) reaches the VPC endpoint ENIs, and (6) PrivateLink forwards the request to the service.

Pattern 4: Cross-account access with an endpoint in each consumer VPC

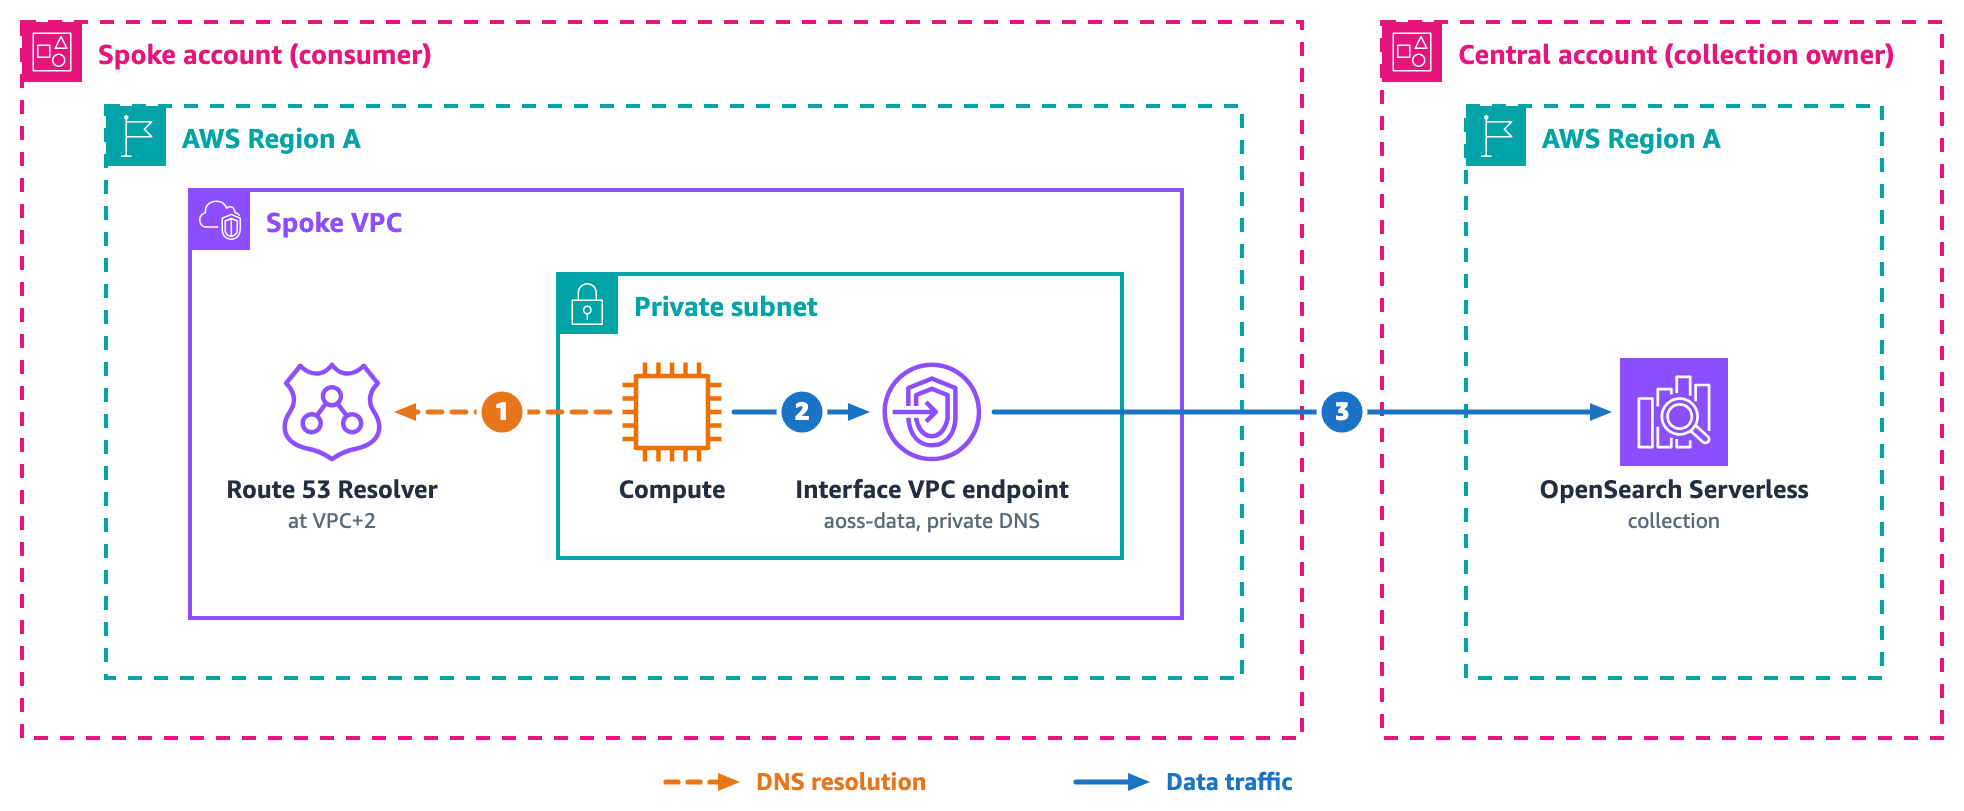
A central account hosts collections, and compute in spoke accounts needs private access. Many enterprises start here. The following diagram shows the cross-account endpoint architecture.
Spoke accounts each with their own interface endpoint reaching collections in a central account over PrivateLink

Figure 4: Cross-account access with an endpoint in each consumer VPC

Each spoke creates its own endpoint. The collection owner’s network policy references the spoke’s endpoint ID. The data access policy grants the spoke’s IAM role. PrivateLink carries the traffic end to end, with no Transit Gateway and no peering.

The endpoint lives in the spoke account, not the collection account. The spoke team creates a standard interface VPC endpoint in the spoke VPC for the service name com.amazonaws.<region>.aoss-data with private DNS enabled. The collection owner does not create this endpoint. After the endpoint is ready the spoke shares its endpoint ID with the collection owner, who adds that ID to the collection network policy under SourceVPCEs. A network policy accepts endpoint IDs from accounts across your organization. Each spoke creates its own endpoint and shares the ID rather than peering VPCs or routing through another account’s endpoint.

Network access and data access stay separate. The network policy authorizes the endpoint, and the data access policy authorizes the identity. A serverless data access policy grants principals from the collection’s own account. For a spoke in another account, you create an IAM role in the collection account and grant that role in the data access policy. The spoke role then assumes it to sign requests.

The following network access policy lists the two spoke endpoint IDs under SourceVPCEs and sets AllowFromPublic to false, so only those endpoints reach the collection and the policy denies public access.

[
  {
    "Description": "Cross-account access from spoke",
    "Rules": [
      {
        "ResourceType": "collection",
        "Resource": [
          "collection/my-collection"
        ]
      }
    ],
    "AllowFromPublic": false,
    "SourceVPCEs": [
      "vpce-spoke-b-id",
      "vpce-spoke-c-id"
    ]
  }
]

For the DNS resolution flow, (1) spoke compute queries the VPC Route 53 Resolver at VPC+2, which returns the local endpoint ENI IPs because private DNS is enabled on the endpoint.

For the data traffic path, (2) compute connects to the local ENI. (3) PrivateLink forwards the request to the service, which checks the network policy for the endpoint ID and the data access policy for the IAM role before routing. Adding a spoke takes one API call and two policy edits.

Pattern 5: Centralized shared endpoint with Amazon Route 53 Profiles over Transit Gateway

You want fewer PrivateLink endpoints, so you run one shared endpoint in a networking VPC and reach it from spoke accounts over Transit Gateway or AWS Cloud WAN, with no endpoint in each spoke. The following diagram shows this centralized architecture.
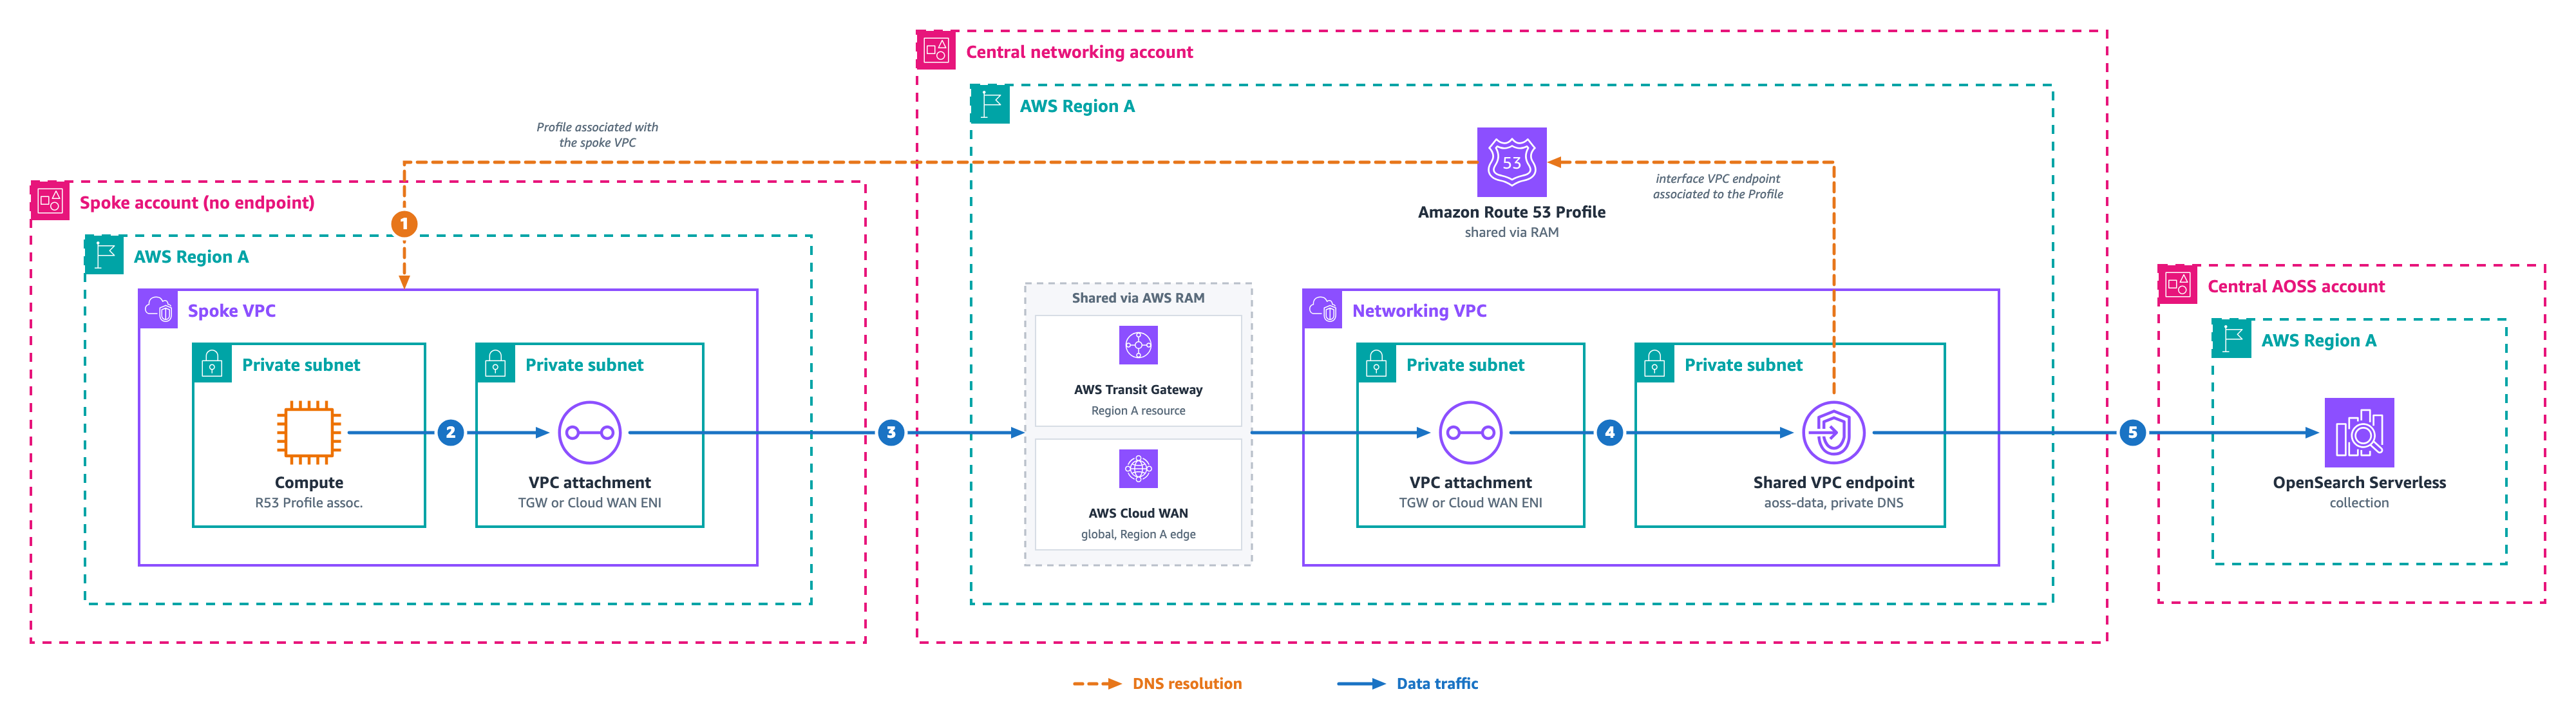
Figure 5: Centralized shared endpoint with Amazon Route 53 Profiles over Transit Gateway

Pattern 5 consolidates access through a single shared endpoint in a central networking VPC rather than creating one per spoke. Because spoke VPCs have no local endpoint, they cannot resolve *.aoss.<region>.on.aws on their own. You share the endpoint’s private DNS with spoke VPCs using Amazon Route 53 Profiles, shared through AWS Resource Access Manager (AWS RAM). This is the one pattern where you still manage DNS propagation.

For the DNS resolution flow, (1) the spoke resolves the hostname through the shared Route 53 Profile, which returns the networking-VPC endpoint ENI IPs.

For the data traffic path, (2) traffic leaves the compute through the spoke VPC’s attachment ENI, (3) crosses Transit Gateway or Cloud WAN into the networking VPC’s attachment ENI, (4) reaches the shared endpoint ENIs, and (5) PrivateLink forwards the request to the service.

Pattern 6: Cross-account centralized networking with on-premises

A central account hosts collections. A separate networking account owns Direct Connect or VPN and Route 53. On-premises clients reach the collections through the networking account. The following diagram shows this architecture.
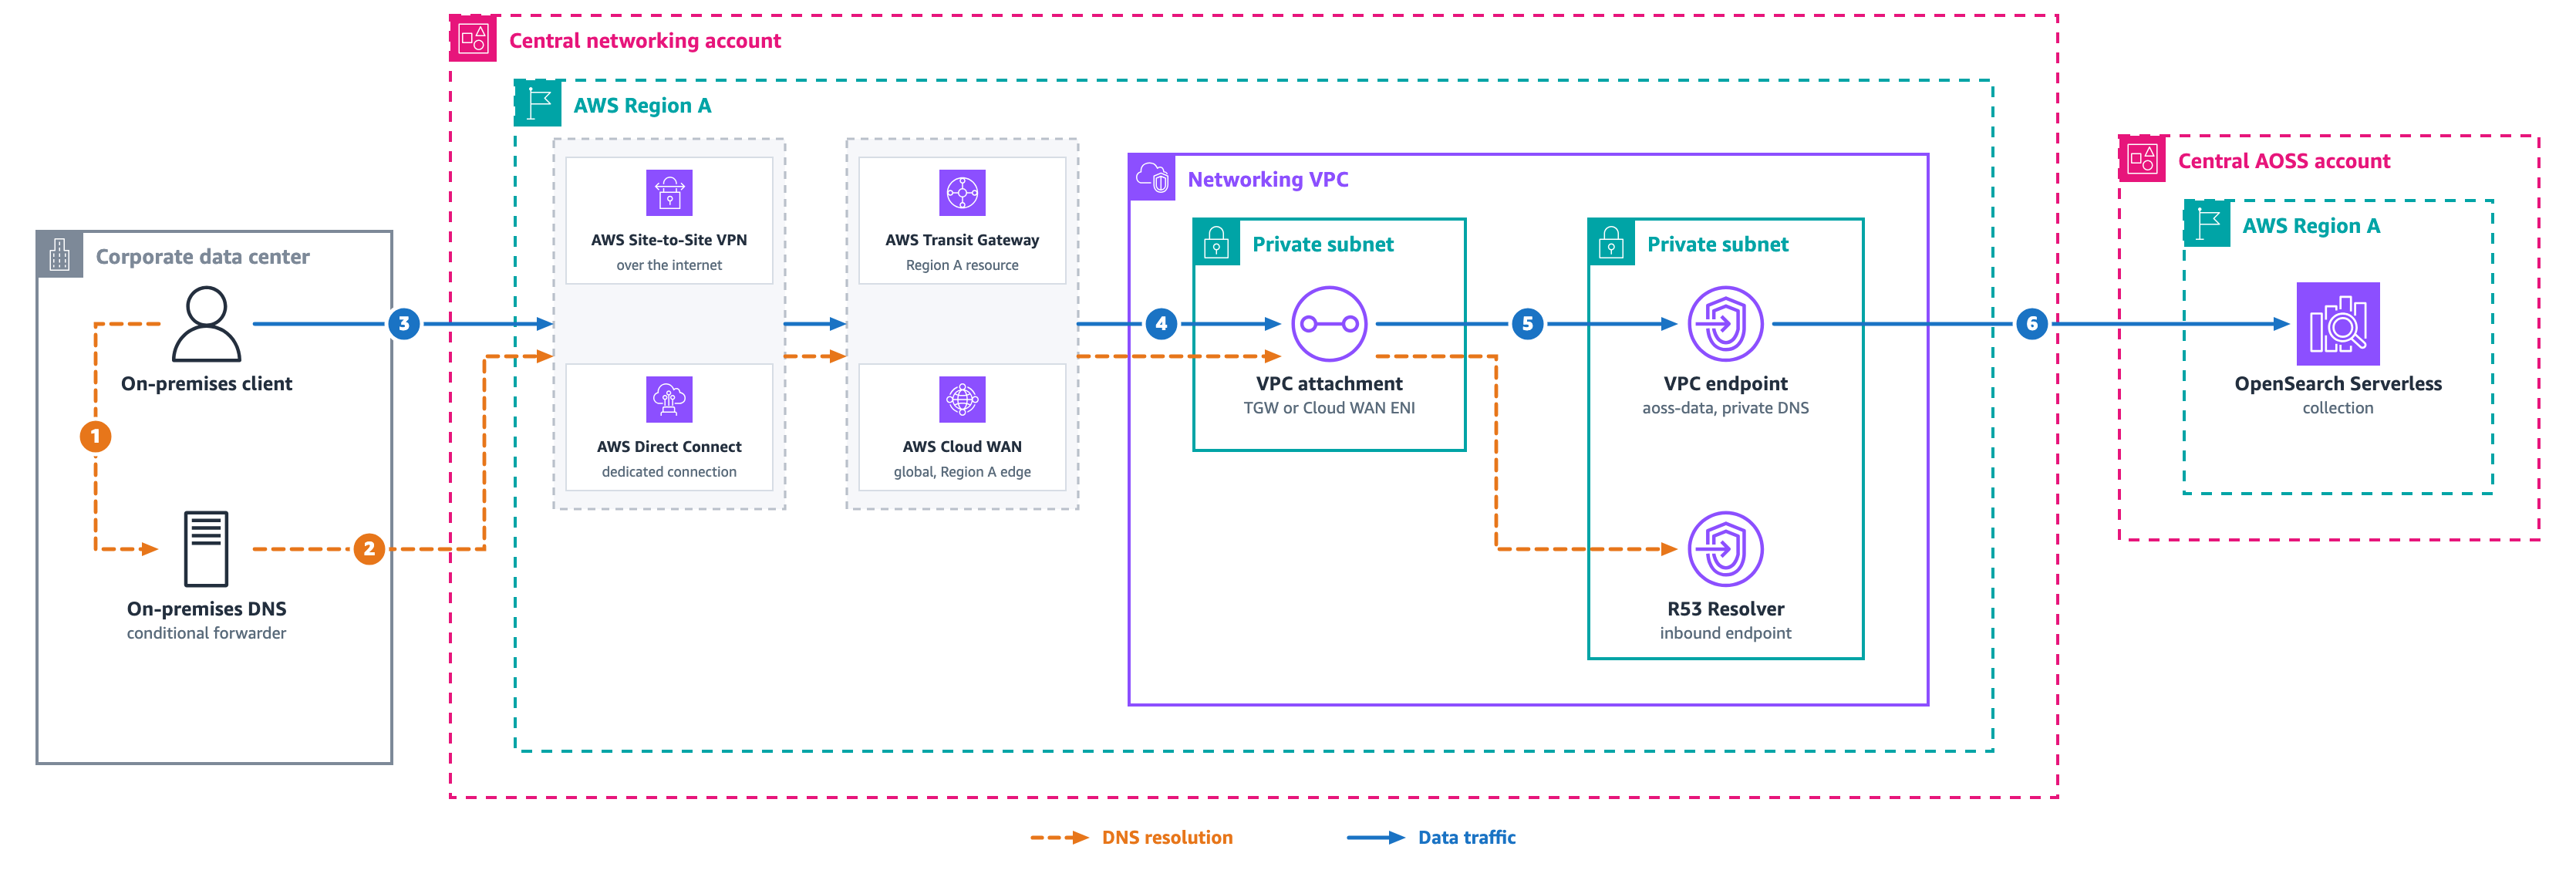
Figure 6: Cross-account centralized networking with on-premises

The networking account runs the standard VPC endpoint and a Route 53 Resolver inbound endpoint. The collection owner’s network policy references the networking account’s endpoint ID.

For the DNS resolution flow, (1) the on-premises client queries its resolver. (2) The on-premises conditional forwarder sends the query over Direct Connect or VPN, through Transit Gateway or Cloud WAN, to the inbound endpoint. The inbound endpoint uses the VPC Route 53 Resolver to return the endpoint’s private ENI IPs.

For the data traffic path, (3) the client sends HTTPS over Direct Connect or VPN, through Transit Gateway or Cloud WAN. (4) Traffic crosses the networking VPC’s attachment ENI, (5) reaches the networking-VPC endpoint ENIs, and (6) PrivateLink forwards the request to the service in the central account. The two teams coordinate through one artifact, the endpoint ID.

Pattern 7: Distributed multi-business-unit with spoke-account access

Spoke accounts such as analytics or application teams need collections spread across several business unit accounts, and each unit manages its own collections. The following diagram shows the distributed multi-business-unit architecture.
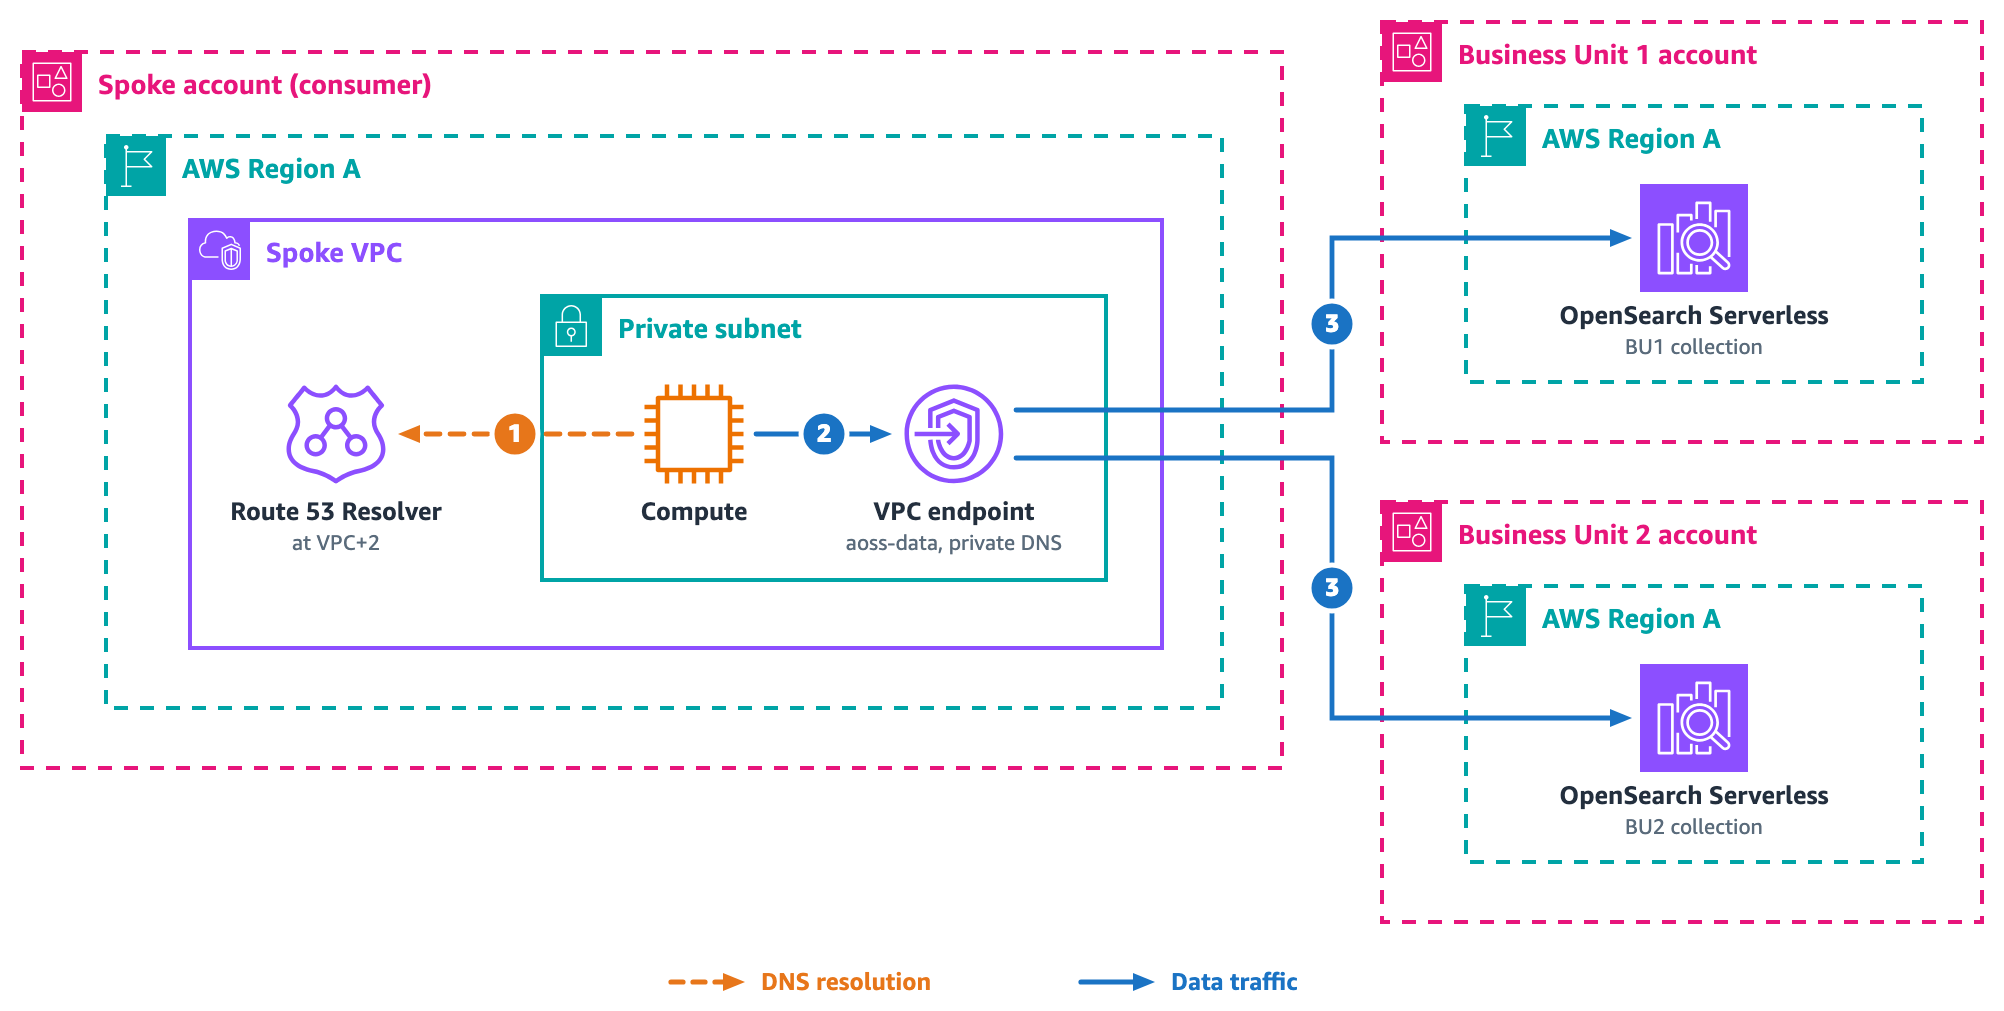
Spoke accounts reaching collections spread across several business unit accounts, each spoke with its own endpoint

Figure 7: Distributed multi-business-unit with spoke-account access

Each spoke creates one standard endpoint, which resolves every collection hostname in the Region. Each business unit’s network policy lists the spoke endpoint IDs. Access control decides which collections a spoke reaches. DNS does not.

For the DNS resolution flow, (1) spoke compute queries the VPC Route 53 Resolver at VPC+2, which returns the endpoint ENI IPs because private DNS is enabled on the endpoint.

For the data traffic path, (2) compute connects to the local ENI, and (3) PrivateLink forwards the request to the service, which routes to the correct business unit collection by hostname.

Action Required change
New collection in any BU No networking change is needed because in the network policy collection/*  wildcard, already covers any new collection
New spoke account Spoke creates an endpoint, and BUs add its ID to their policies
Remove spoke access BUs remove the endpoint ID and the IAM principal

Pattern 8: Distributed multi-business-unit with on-premises access

Several business units own collections in separate accounts. On-premises clients reach collections across all of those accounts through a central networking account. The following diagram shows this architecture.
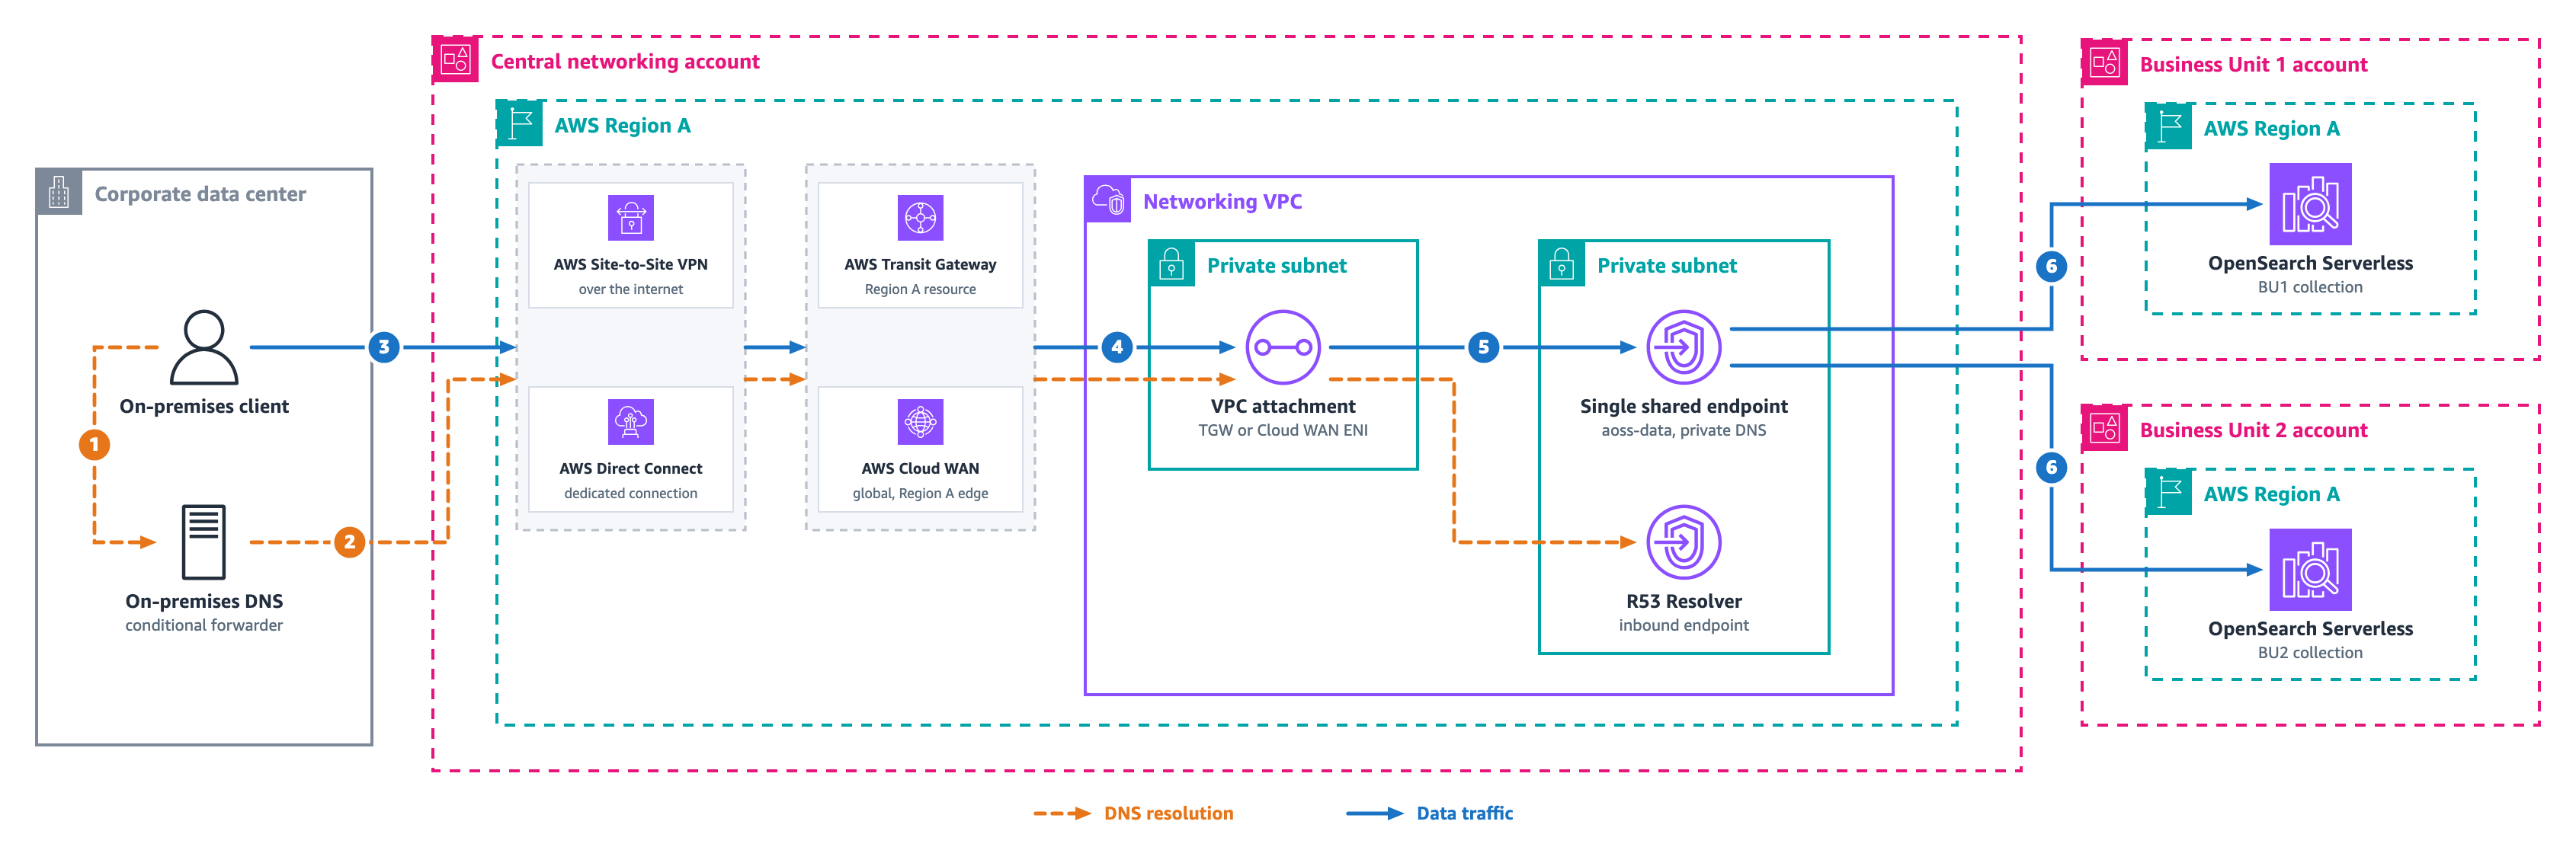
Figure 8: Distributed multi-business-unit with on-premises access

The networking account runs one standard endpoint that resolves *.aoss.<region>.on.aws hostnames, regardless of which account owns the collection. Each business unit’s network policy includes the networking endpoint ID.

For the DNS resolution flow, (1) the on-premises client queries its resolver. (2) The on-premises conditional forwarder for *.aoss.<region>.on.aws sends the query over Direct Connect or VPN, through Transit Gateway or Cloud WAN, to the networking VPC’s inbound endpoint. The inbound endpoint uses the VPC Route 53 Resolver to return the shared endpoint’s private ENI IPs.

For the data traffic path, (3) the client sends HTTPS over Direct Connect or VPN, through Transit Gateway or Cloud WAN. (4) Traffic crosses the networking VPC’s attachment ENI, (5) the request arrives at the shared endpoint ENIs, and (6) the service routes to business unit 1 or business unit 2 by hostname, as long as that business unit’s policy lists the networking endpoint ID. Adding a collection in any business unit needs no networking change if the network policy uses a collection/* wildcard, since the wildcard already covers it.

Pattern 9: Cross-Region access strategies

Consumers in Region B need data that lives in collections in Region A. The following diagram shows cross-Region access strategies.
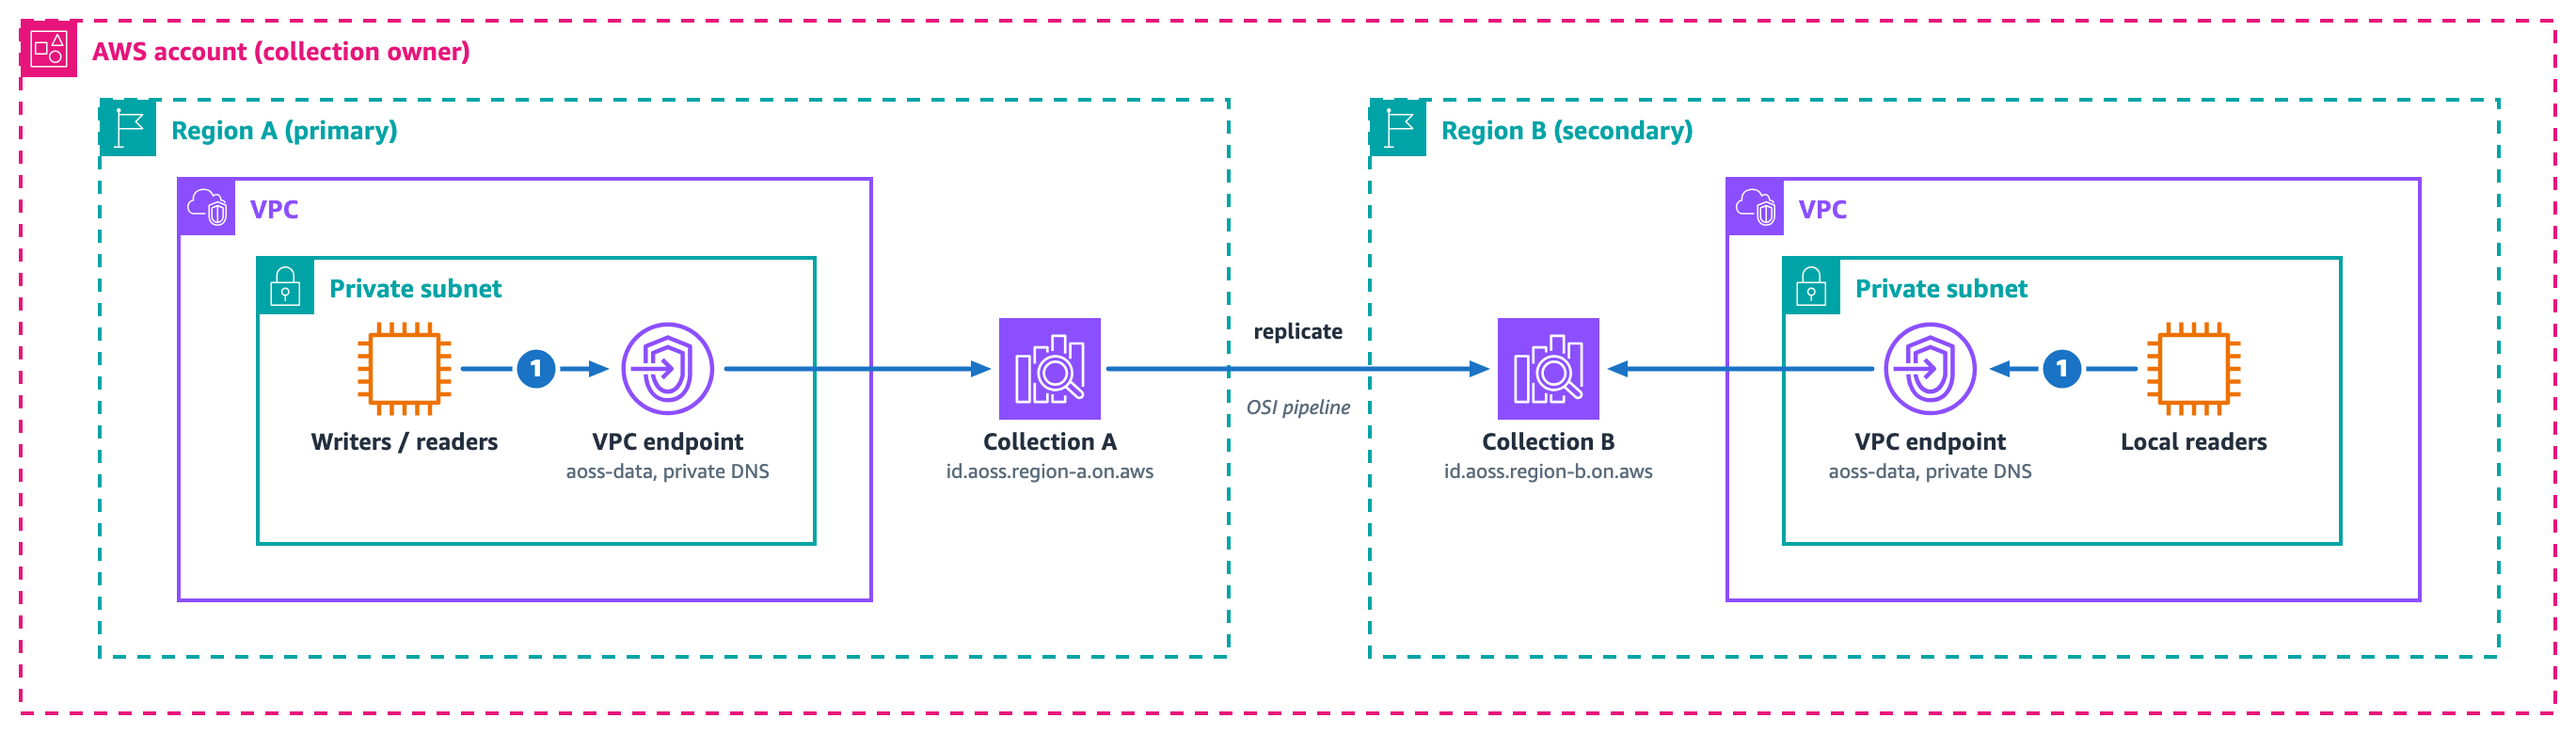
Independent collections in Region A and Region B, each with its own endpoint, with a replication arrow showing cross-Region data sync

Figure 9: Cross-Region access strategies

Collections are Regional. No built-in cross-Region endpoint or replication exists. Deploy independent collections in each Region, each with its own endpoint and policies, then synchronize data with one of these approaches.

  • Dual-write. The application writes to both Regions at ingestion time.
  • Amazon OpenSearch Ingestion pipeline. A pipeline replicates index operations to the secondary Region with near real-time lag. The pipeline creates its own PrivateLink endpoint to the destination collection. It adds the endpoint to that collection’s network policy automatically. You only need to name the network policy and grant the pipeline role.
  • Amazon Simple Storage Service (Amazon S3) Cross-Region Replication with re-ingestion. Cross-Region Replication copies objects, and an OpenSearch Ingestion pipeline loads them into the local collection. Lag runs in minutes, at the lowest cost of these approaches.

For the DNS resolution flow, DNS resolves locally in each Region, the same as Pattern 1. Each collection hostname carries its Region, so a hostname in Region A resolves through Region A’s own endpoint and a hostname in Region B resolves through Region B’s own endpoint, with no cross-Region DNS.

For the data traffic path, (1) compute in each Region uses that Region’s own endpoint to reach its local collection. Writes land in the primary Region and the sync approach you choose replicates them to the secondary Region, where local readers query the replica. The replicate arrow shows that cross-Region movement, such as an OpenSearch Ingestion pipeline that writes into the secondary-Region collection.

Scale-to-zero changes the economics. An idle secondary-Region collection costs only storage until requests arrive.

Summary

Pattern Components
1. Same VPC Standard endpoint and network policy
2. Multiple VPCs Endpoint per VPC and a policy listing all IDs
3. On-premises Endpoint, Route 53 inbound endpoint, on-premises forwarder, and Transit Gateway or Cloud WAN
4. Cross-account Endpoint per consumer, network policy, and data policy
5. Centralized shared endpoint Shared endpoint, Route 53 Profiles through RAM, and Transit Gateway or Cloud WAN
6. Central networking with on-premises Networking endpoint, Route 53 inbound, forwarder, Transit Gateway or Cloud WAN, and policies
7. Multi-BU with spoke access Endpoint per spoke, and each BU policy lists spoke IDs
8. Multi-BU with on-premises One networking endpoint reached through Transit Gateway or Cloud WAN, and each BU policy lists its ID
9. Cross-Region Independent collections per Region and a data-sync approach

Across each private pattern, the VPC endpoint resolves all *.aoss.<region>.on.aws hostnames through standard PrivateLink private DNS. Network policies control which endpoints reach a collection, and data access policies control which principals operate on the data. Only Pattern 5 asks you to manage DNS.

Cost considerations

The connectivity pattern you choose drives recurring cost, so match it to your scale instead of adding infrastructure you do not need. The two charges that come up most often, a Route 53 Resolver inbound endpoint and Route 53 Profiles, are both optional for access that stays inside AWS.

A Route 53 Resolver inbound endpoint is needed only for the on-premises patterns (3, 6, and 8), where an on-premises resolver forwards queries into the VPC. Traffic that stays inside AWS never uses it. Route 53 Profiles apply only when a VPC has no endpoint of its own, as in Pattern 5, where the profile carries the shared endpoint’s private DNS to the spoke. When each VPC runs its own interface endpoint, DNS resolves locally through the VPC Route 53 Resolver at no extra charge, so neither the inbound endpoint nor a profile is required.

For most multi-account and multi-Region deployments, an interface endpoint in each consumer VPC (Pattern 4) is the least complex and often the least expensive option. You pay for the interface endpoints you already need for private access, and local DNS resolution adds nothing. Because collections are Regional and each Region resolves on its own, this scales across Regions with no cross-Region DNS.

Centralizing on one shared endpoint (Pattern 5) lowers the number of interface endpoints. However, it adds Transit Gateway or Cloud WAN data processing charges and the cost of sharing DNS. You share that DNS either through Route 53 Profiles or through a private hosted zone that you associate across accounts and maintain yourself. A smaller endpoint count is not automatically cheaper because transit data processing can exceed the savings. Compare both designs against your own traffic before you decide.

Scale to zero also shapes cost. An idle collection, such as a secondary-Region replica in Pattern 9, releases its compute and bills only for storage until requests arrive. For current rates, see AWS PrivateLink pricing, Amazon Route 53 pricing, and Amazon OpenSearch Service pricing.

Conclusion

OpenSearch Serverless uses standard AWS PrivateLink for private connectivity. You create a VPC endpoint, enable private DNS, and reference the endpoint ID in your network policy. The model scales from single-VPC access to multi-account and multi-business-unit designs, and only Pattern 5 adds DNS infrastructure, where you share the endpoint’s private DNS with Route 53 Profiles. The per-account regional endpoint goes further and serves any collection in an account through one hostname and connection pool. To get started, create your first collection in the OpenSearch Serverless console, or explore the OpenSearch Serverless documentation for detailed API references and tutorials.
About the authors

Salman Ahmed

Salman Ahmed

Salman is a Senior Technical Account Manager at AWS, specializing in helping customers design, implement, and optimize their AWS environments. He combines deep networking expertise with a passion for exploring emerging technologies to help organizations get the most out of their cloud investments. Outside of work, he enjoys photography, traveling, and watching his favorite sports teams.

Ankush Goyal

Ankush Goyal

Ankush is a Senior Technical Account Manager at AWS Enterprise Support, specializing in helping customers in the travel and hospitality industries optimize their cloud infrastructure. With over 20 years of IT experience, he focuses on using AWS networking services to drive operational efficiency and cloud adoption. Ankush is passionate about delivering impactful solutions and helping clients to streamline their cloud operations.

Ravi Bhatane

Ravi Bhatane

Ravi is a Software Engineer at AWS working on Amazon OpenSearch Serverless. He builds the gateway layer that fronts the service, handling private connectivity, authentication, and request routing for customer traffic into collections. He’s drawn to distributed systems and the challenge of keeping them secure, highly available, and low latency as they grow. Outside of work, he enjoys photography and hiking.

Accelerating AWS Network Firewall troubleshooting with AWS DevOps Agent

Post Syndicated from Salman Ahmed original https://aws.amazon.com/blogs/security/accelerating-aws-network-firewall-troubleshooting-with-aws-devops-agent/

When an administrator introduces a rule change in AWS Network Firewall and network connectivity is disrupted, pinpointing the cause requires inspecting multiple points in the traffic path. The firewall gives you stateless and stateful rule engines, domain rules, and routing to the firewall endpoint inside your Amazon Virtual Private Cloud (Amazon VPC). A network drop looks the same from the workload no matter where it started. Isolating the cause means correlating the alert and flow logs with the firewall configuration, route tables, and recent API calls in AWS CloudTrail that might have changed them. That manual correlation is exactly where AWS DevOps Agent helps, accelerating root cause analysis so you can restore connectivity in minutes instead of hours.

AWS DevOps Agent does that correlation for you. As your always-available operations teammate, it resolves and proactively prevents operational issues across AWS, multicloud, and on-premises environments. When an Amazon CloudWatch alarm triggers, it reaches the agent through a webhook. The agent then reads the firewall configuration and logs through AWS APIs, ties the drop to recent API activity, and returns a root cause with a mitigation plan you review before you apply it.

This post connects CloudWatch monitoring to DevOps Agent. It walks through three Network Firewall failures from end to end. The first is a domain deny list blocking a legitimate endpoint. The second is a stateless rule priority misconfiguration. The third is an asymmetric cross Availability Zone (AZ) routing drop. Each maps to a different layer, so each leads down a different investigation path. An AWS Cloud Development Kit (AWS CDK) app deploys the whole environment in your own account so you can reproduce each failure and follow along.

The sample workload

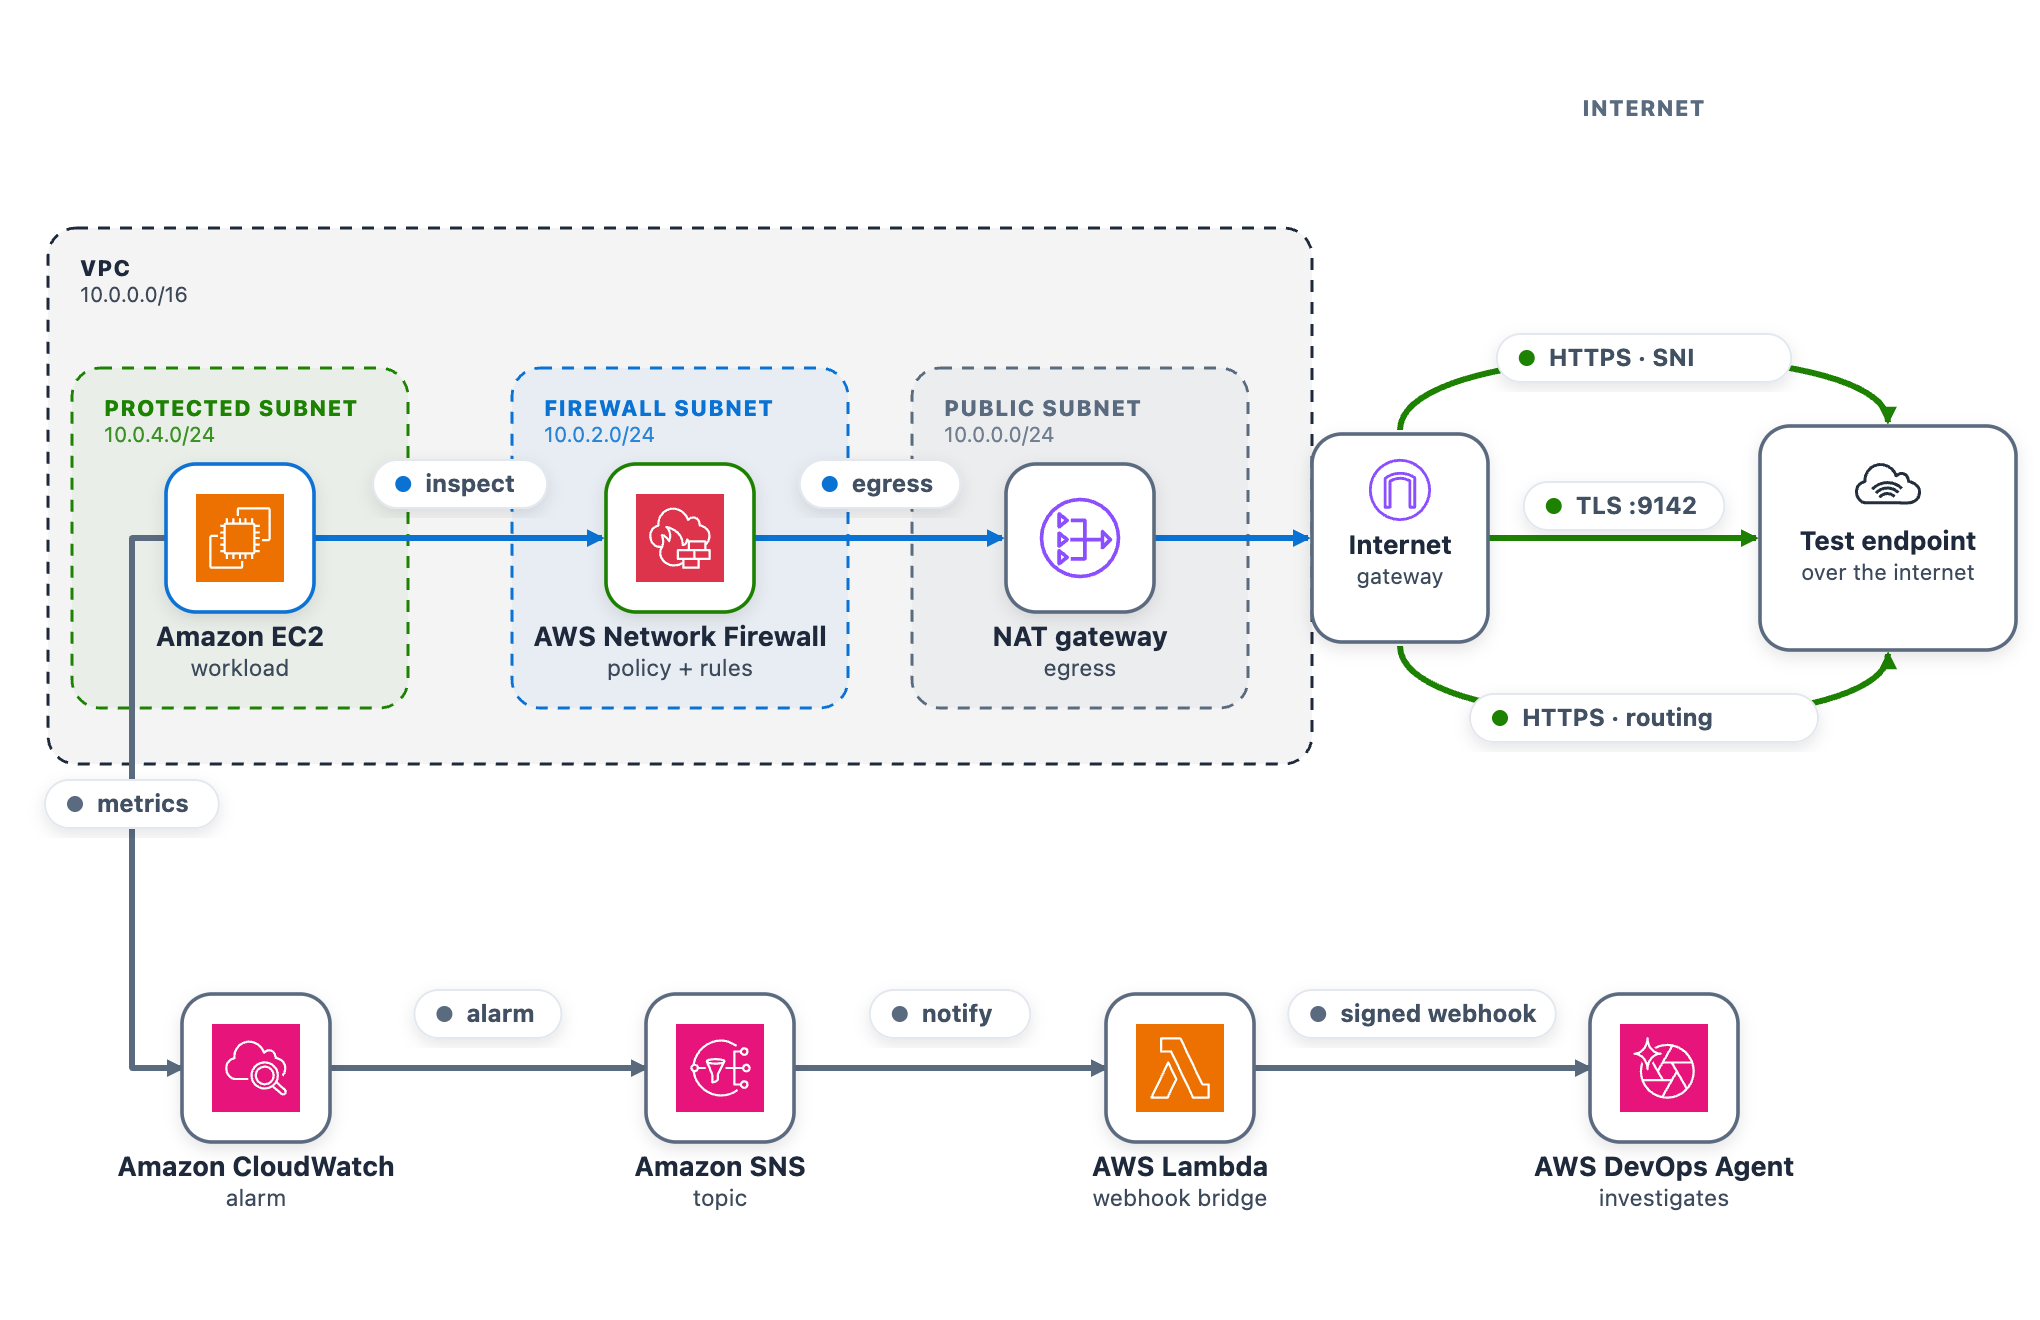
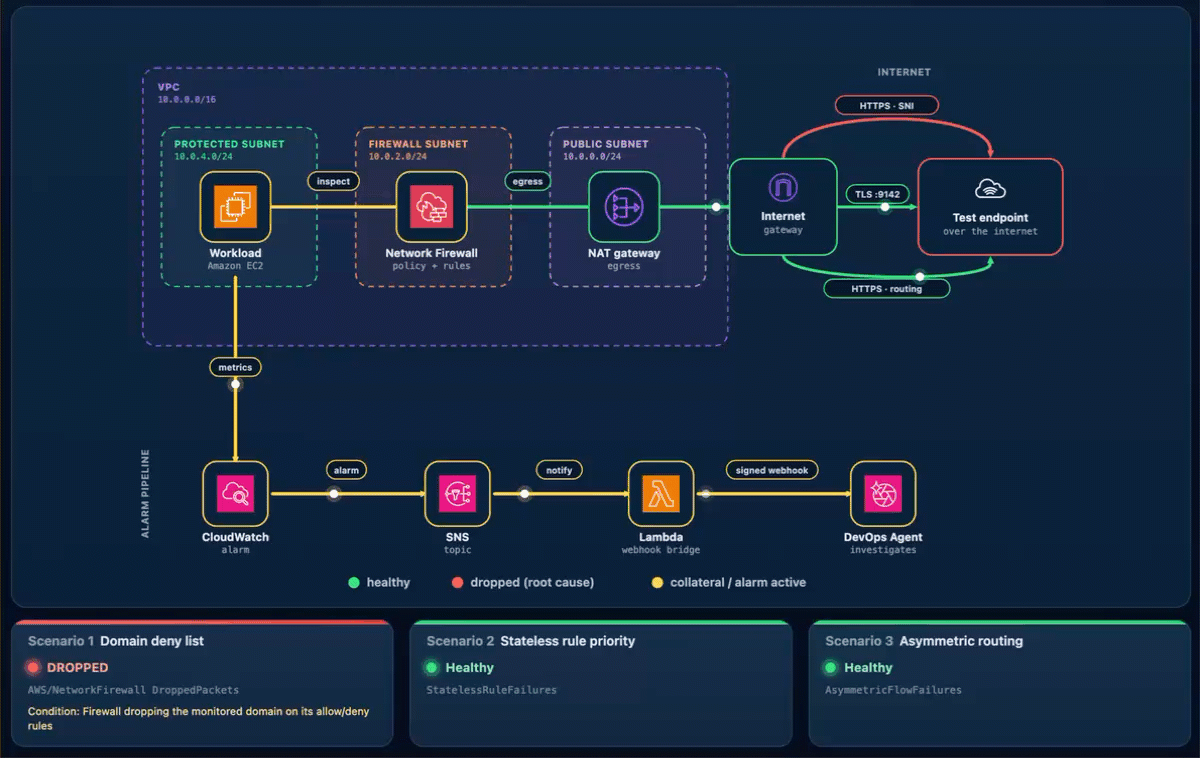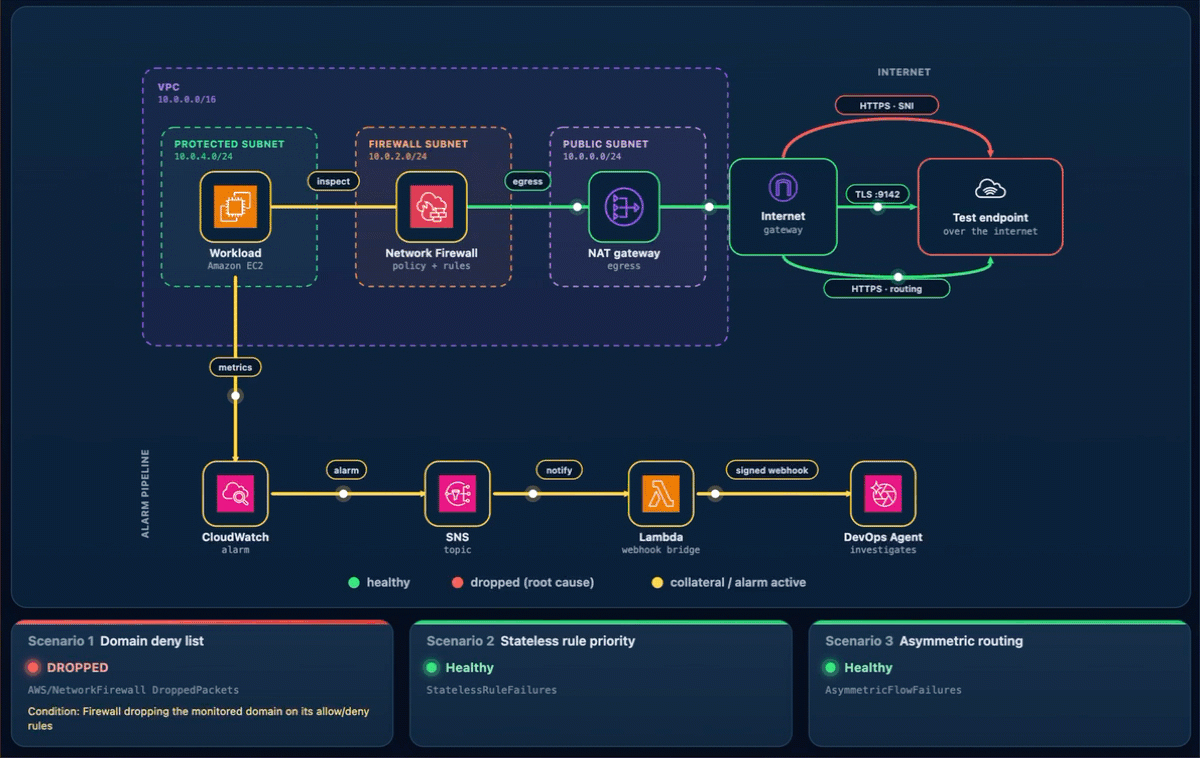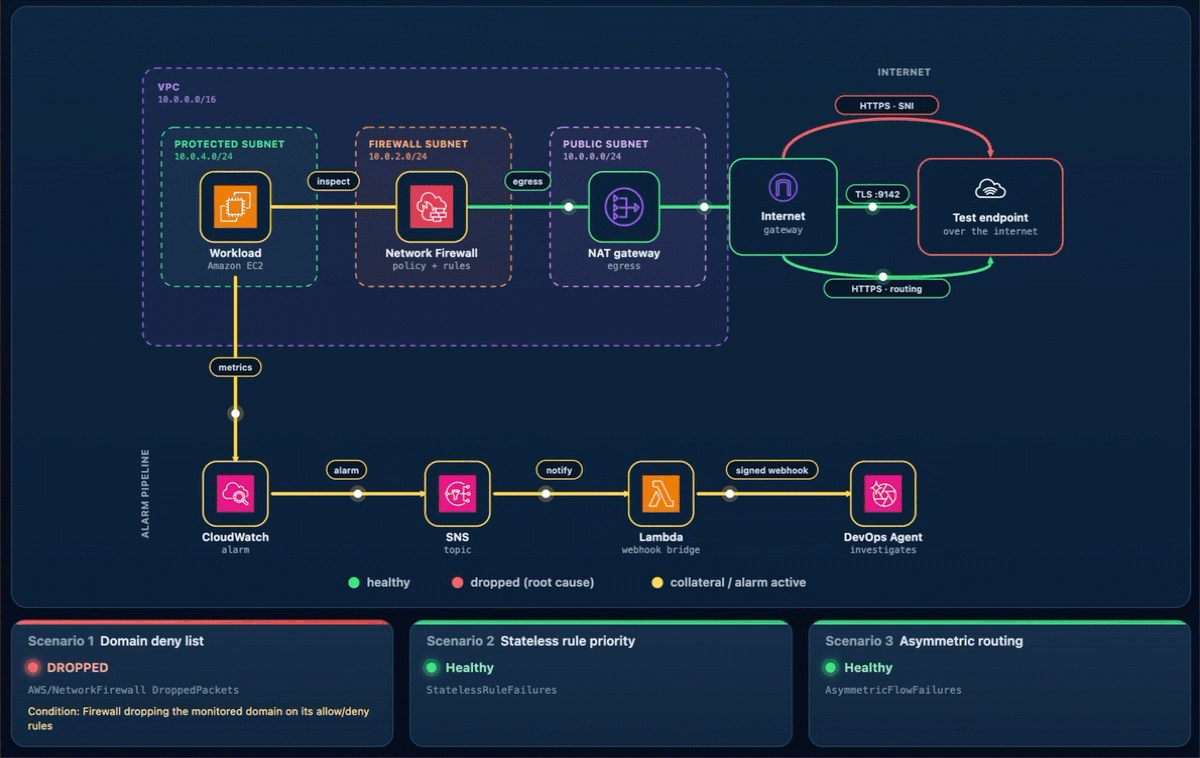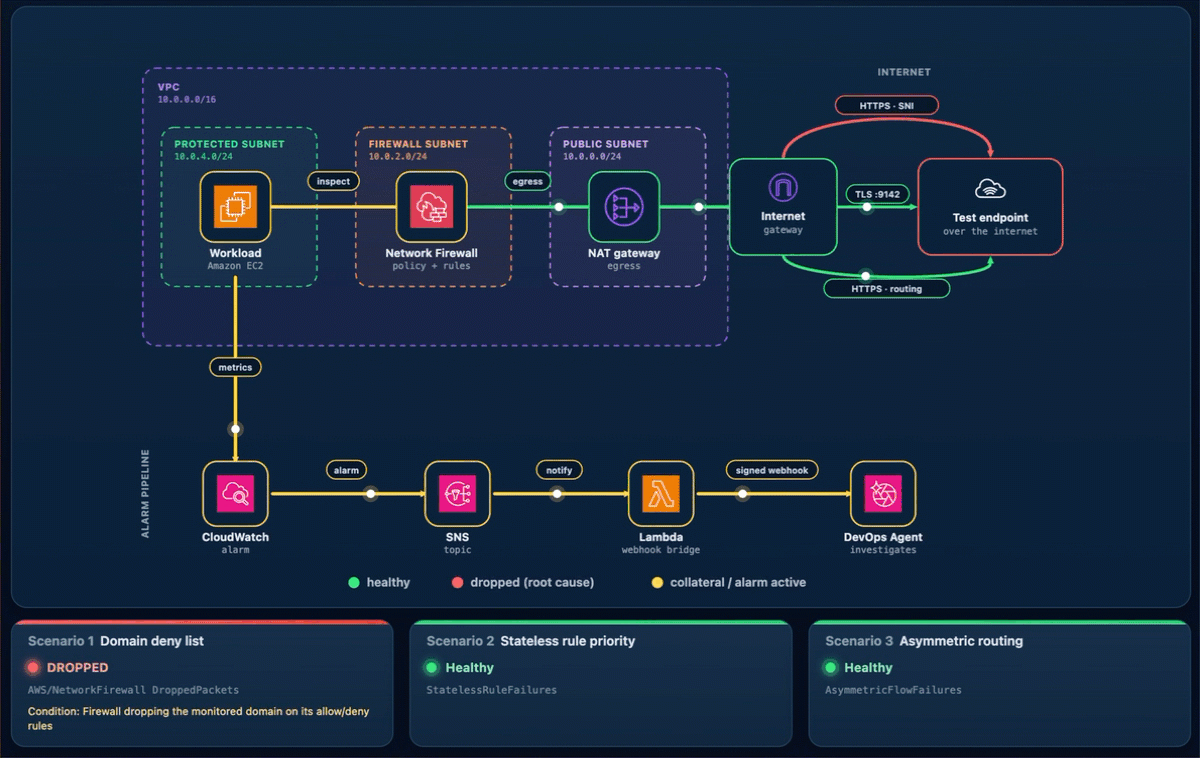
As part of this blog post, we provide a CDK stack that deploys both the AWS DevOps Agent Space and a sample workload used to walk through three separate troubleshooting scenarios. A single t3.micro instance in a protected subnet checks its connectivity to a test endpoint on a continuous loop and publishes results to CloudWatch. Traffic takes the internet egress path through Network Firewall, the NAT gateway, and the internet gateway, so the firewall can intercept or drop it. After completing the walkthrough, you can apply the same troubleshooting techniques with DevOps Agent against your own Network Firewall deployments.

The test endpoint runs in a separate VPC deployed by the same CDK app. It serves HTTPS on port 443 and TCP on port 9142, giving each scenario a different protocol layer to exercise: Scenario 1 targets a TLS connection on 443 (matched by Server Name Indication), Scenario 2 targets a TCP connection on 9142, and Scenario 3 exercises the whole egress path.

A live status page shows one card per scenario plus the network topology. The whole stack deploys from a single CDK app across two Availability Zones, each with a firewall endpoint and NAT gateway, which is what makes Scenario 3 possible.

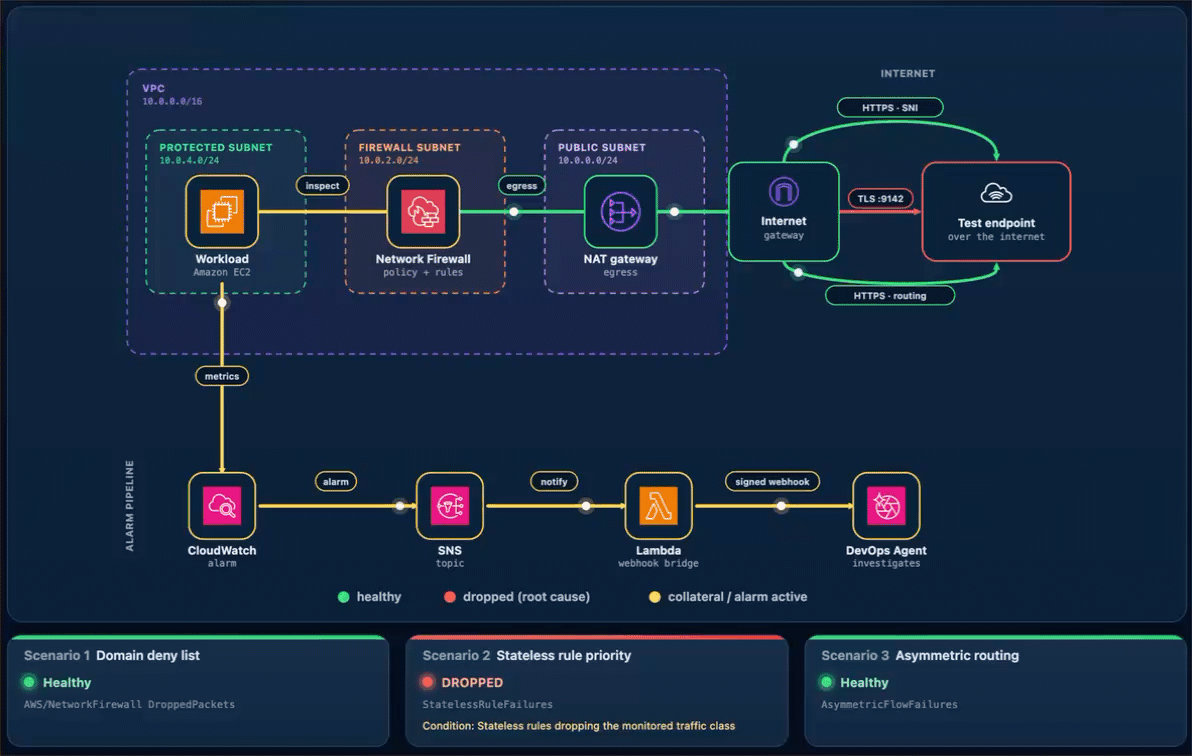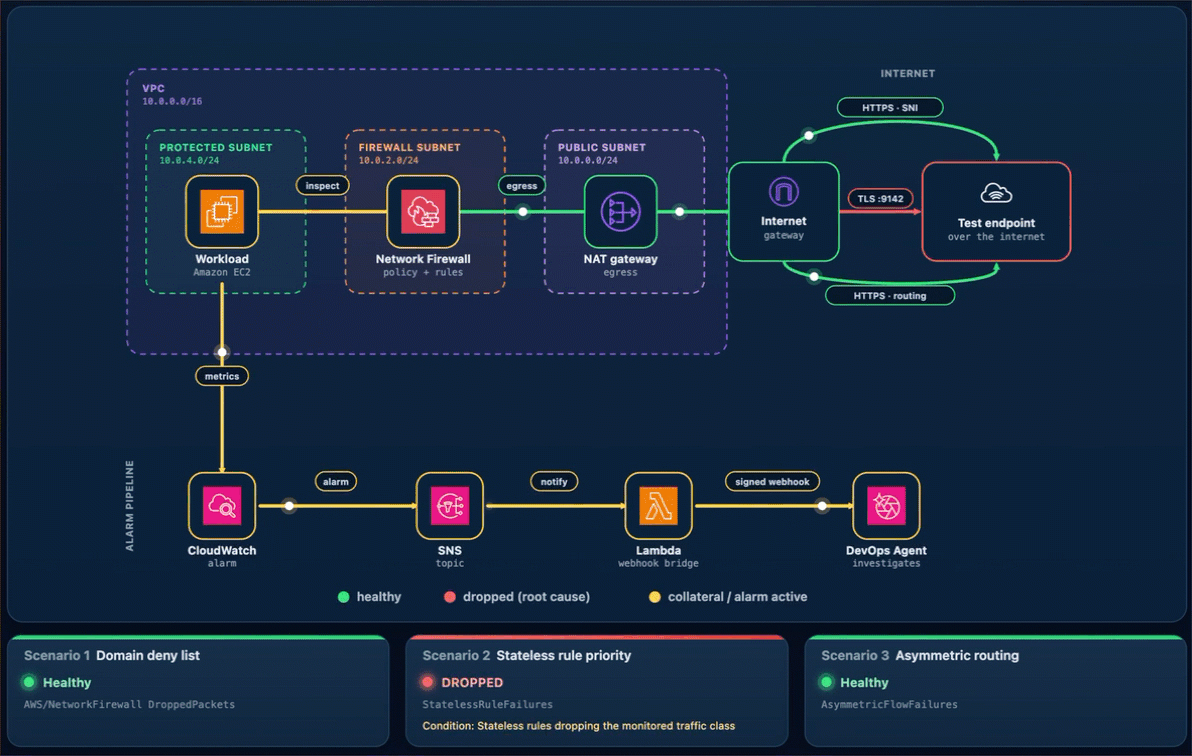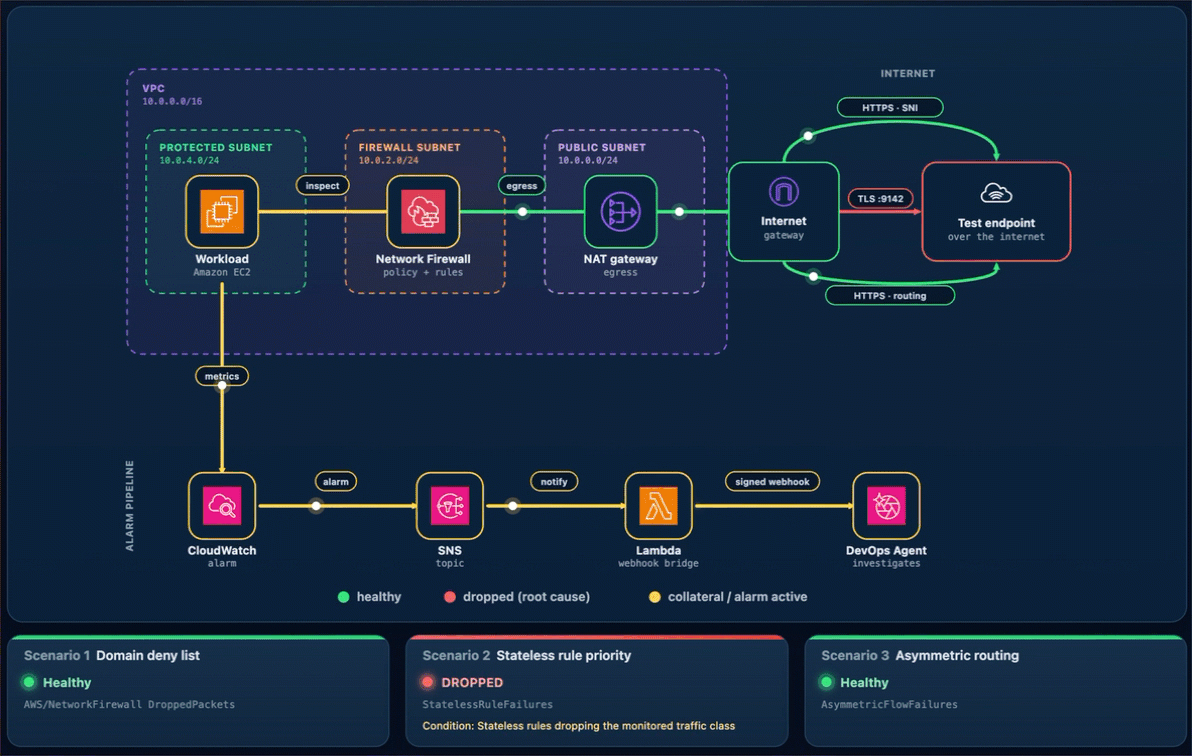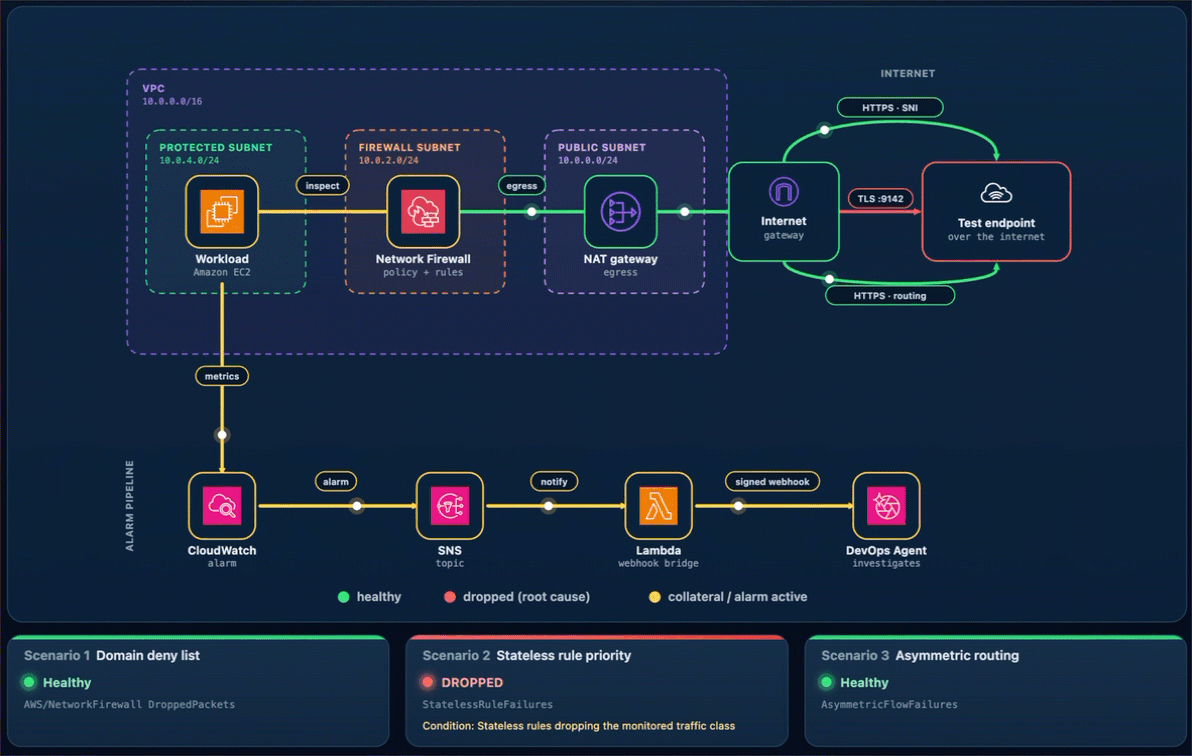
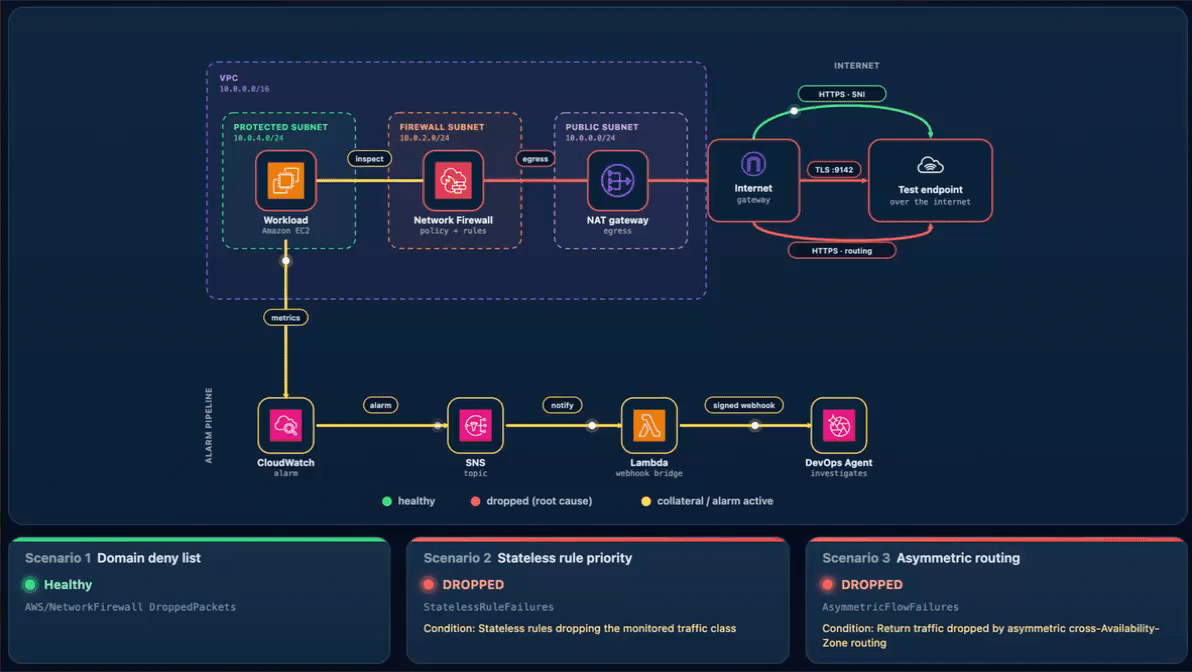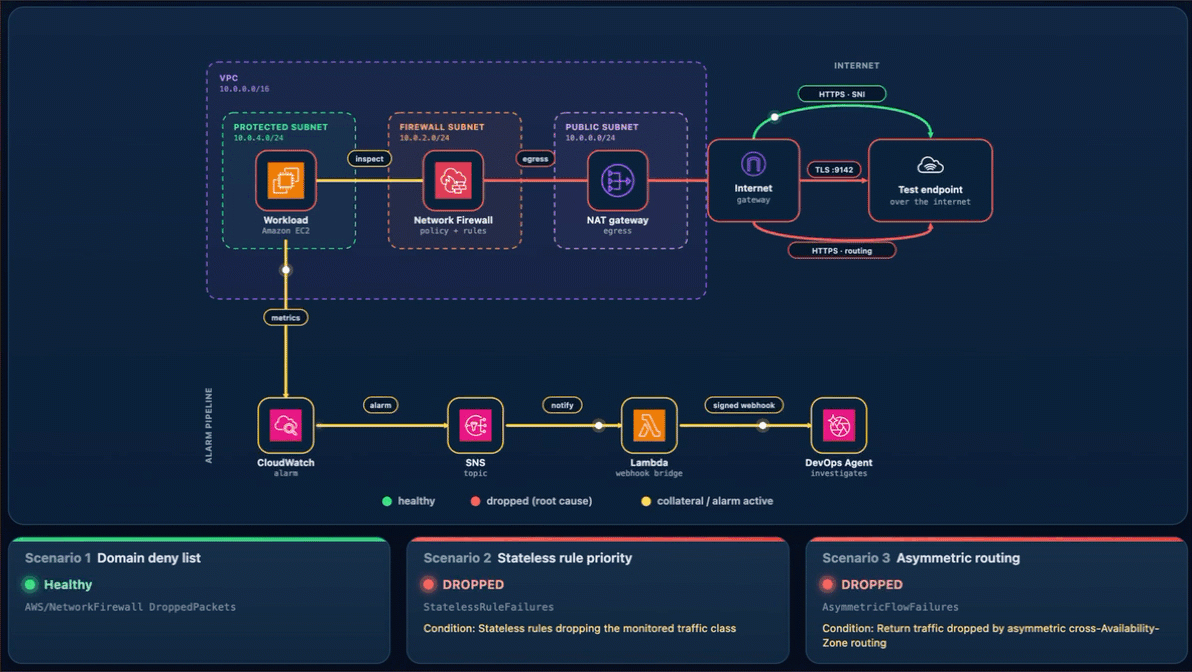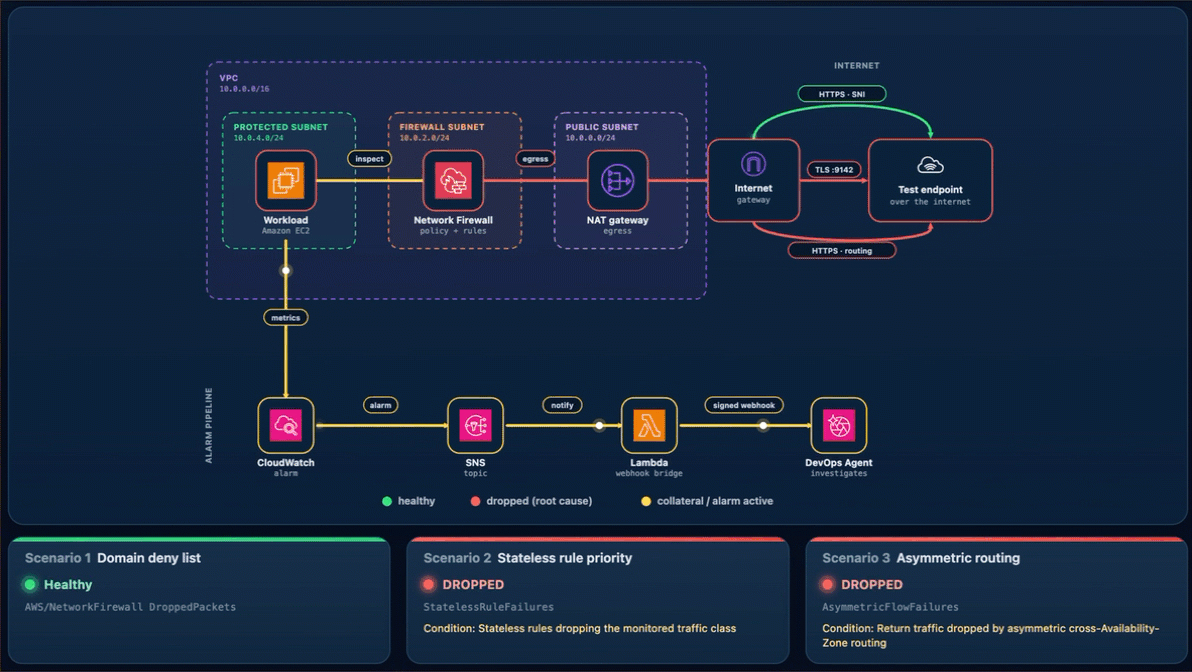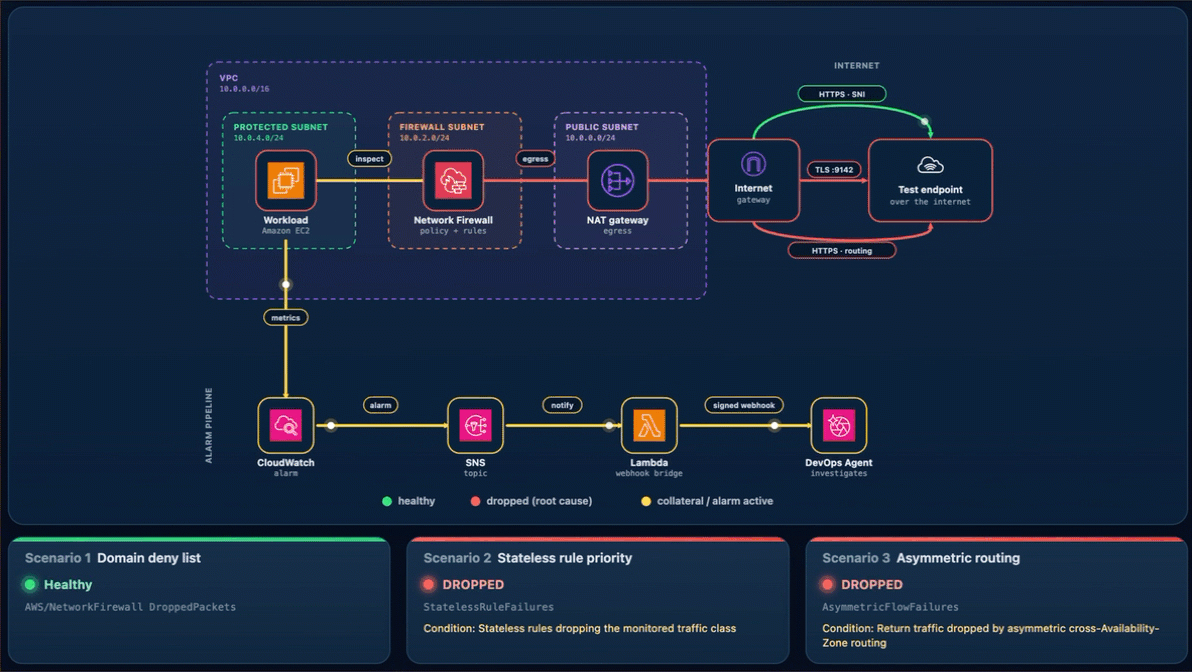
As shown in the following figure, the egress data path runs from the workload through Network Firewall and the NAT and internet gateways to the test endpoint. The alarm pipeline runs from CloudWatch through Amazon Simple Notification Service (Amazon SNS) and the webhook AWS Lambda function to DevOps Agent.

Figure 1: The sample workload

Figure 1: The sample workload

To use this with your own workload, you need a CloudWatch alarm that detects the connectivity problem and the webhook pipeline (SNS topic and Lambda function) that delivers it to DevOps Agent. The agent reads your firewall configuration, logs, and CloudTrail through AWS APIs, so no additional instrumentation is needed on the firewall side.

Prerequisites

To follow along with this post, you need:

Deploy the sample workload

Clone the project and deploy it into us-east-1 with one command (set awsRegion to use another AWS Region).

git clone https://github.com/aws-samples/sample-accelerating-aws-network-firewall-troubleshooting-with-aws-devops-agent.git
cd sample-accelerating-aws-network-firewall-troubleshooting-with-aws-devops-agent
bash scripts/deploy.sh

The script checks prerequisites, installs dependencies, compiles and tests, and bootstraps the CDK if needed. It then deploys all the stacks from a clean baseline and prints the outputs, including the status-page URL and sign-in details.

  1. Open the status-page link (an https://<random-id>.cloudfront.net address).
  2. Sign in using the username and password provided from the CDK output and confirm all three cards show the green Healthy status.
  3. Keep the page open while you run the scenarios.

Connect AWS DevOps Agent

To connect AWS DevOps Agent to the alarm pipeline

  1. In the AWS DevOps Agent console, open the nf-devops-agent-space Agent Space created by the CDK deployment.
  2. Configure the DevOps Agent webhook and download the CSV file with the webhook URL and signing secret.
  3. On the status page, choose Configure webhook, paste the URL and signing secret, and save. The page writes them to the nf-devops-agent-webhook-credentials AWS Secrets Manager secret, so there is no AWS CLI or console step. Until you set it, the bridge Lambda function sees a placeholder and skips delivery.
  4. Verify the path before you run a scenario. In the Lambda console, open nf-devops-agent-webhook and use the Test tab with this event.
    {
      "Records": [
        {
          "Sns": {
            "Message": "{\"AlarmName\":\"TEST-webhook-verification\",\"AlarmDescription\":\"[TEST] Webhook integration test - not a real alarm.\",\"NewStateValue\":\"ALARM\",\"NewStateReason\":\"[TEST] Manual webhook connectivity test. Safe to ignore.\",\"Region\":\"us-east-1\"}"
          }
        }
      ]
    }

  5. A 200 response confirms the path, and a test investigation appears in the DevOps Agent Operator Web App view.

How the alarm pipeline works

Every scenario reaches DevOps Agent the same way. A CloudWatch alarm moves to ALARM and notifies the SNS topic. Amazon SNS invokes a Lambda function. The function reads the webhook URL and signing secret from Secrets Manager, signs an alarm payload, and POSTs it to the DevOps Agent webhook (as shown in Figure 1). Amazon SNS also provides delivery retries, fan-out to other subscribers, and cross-account publishing.

  • Prebuilt Network Firewall metric (Scenario 1) Alarm-1 watches the DroppedPackets metric, summed across the stateful streams, and triggers when drops rise above a baseline threshold. This requires no workload or custom metric and works on an already-deployed firewall. However, it only tells you that the firewall is dropping packets, not which rule is responsible.
  • Application health metric (Scenarios 2 and 3) Alarm-2 and Alarm-3 watch a custom metric from a connectivity check. Use this for an alarm tied to user-facing impact or to tell one traffic path from another, which requires running a component that emits the metric.
Alarm Source Triggers when
Alarm-1 Native AWS/NetworkFirewall DroppedPackets The firewall’s dropped-packet count rises above the baseline
Alarm-2 Custom application health metric The port 9142 (TCP) connectivity check to the test endpoint is being dropped
Alarm-3 Custom application health metric The cross Availability Zone connectivity check is being dropped

Run the scenarios

Work through each of the scenarios one at a time, following the same cycle. Interrupt network connectivity, watch the alarm trigger, let DevOps Agent investigate, apply the recommended fix, and confirm recovery before moving on.

The status-page cards follow the live CloudWatch alarm state. A card shows a green dot and the word Healthy when its alarm is clear, and a red dot and the word DROPPED when its alarm triggers. In the DROPPED state the card also adds a Condition: line describing what’s being dropped, which isn’t shown when the card is healthy. Network Firewall applies changes to new flows, so a change shows within a minute or two. Recovery comes from the mitigation DevOps Agent recommends, which you review and apply.

Scenario 1. Domain deny list blocking a legitimate endpoint

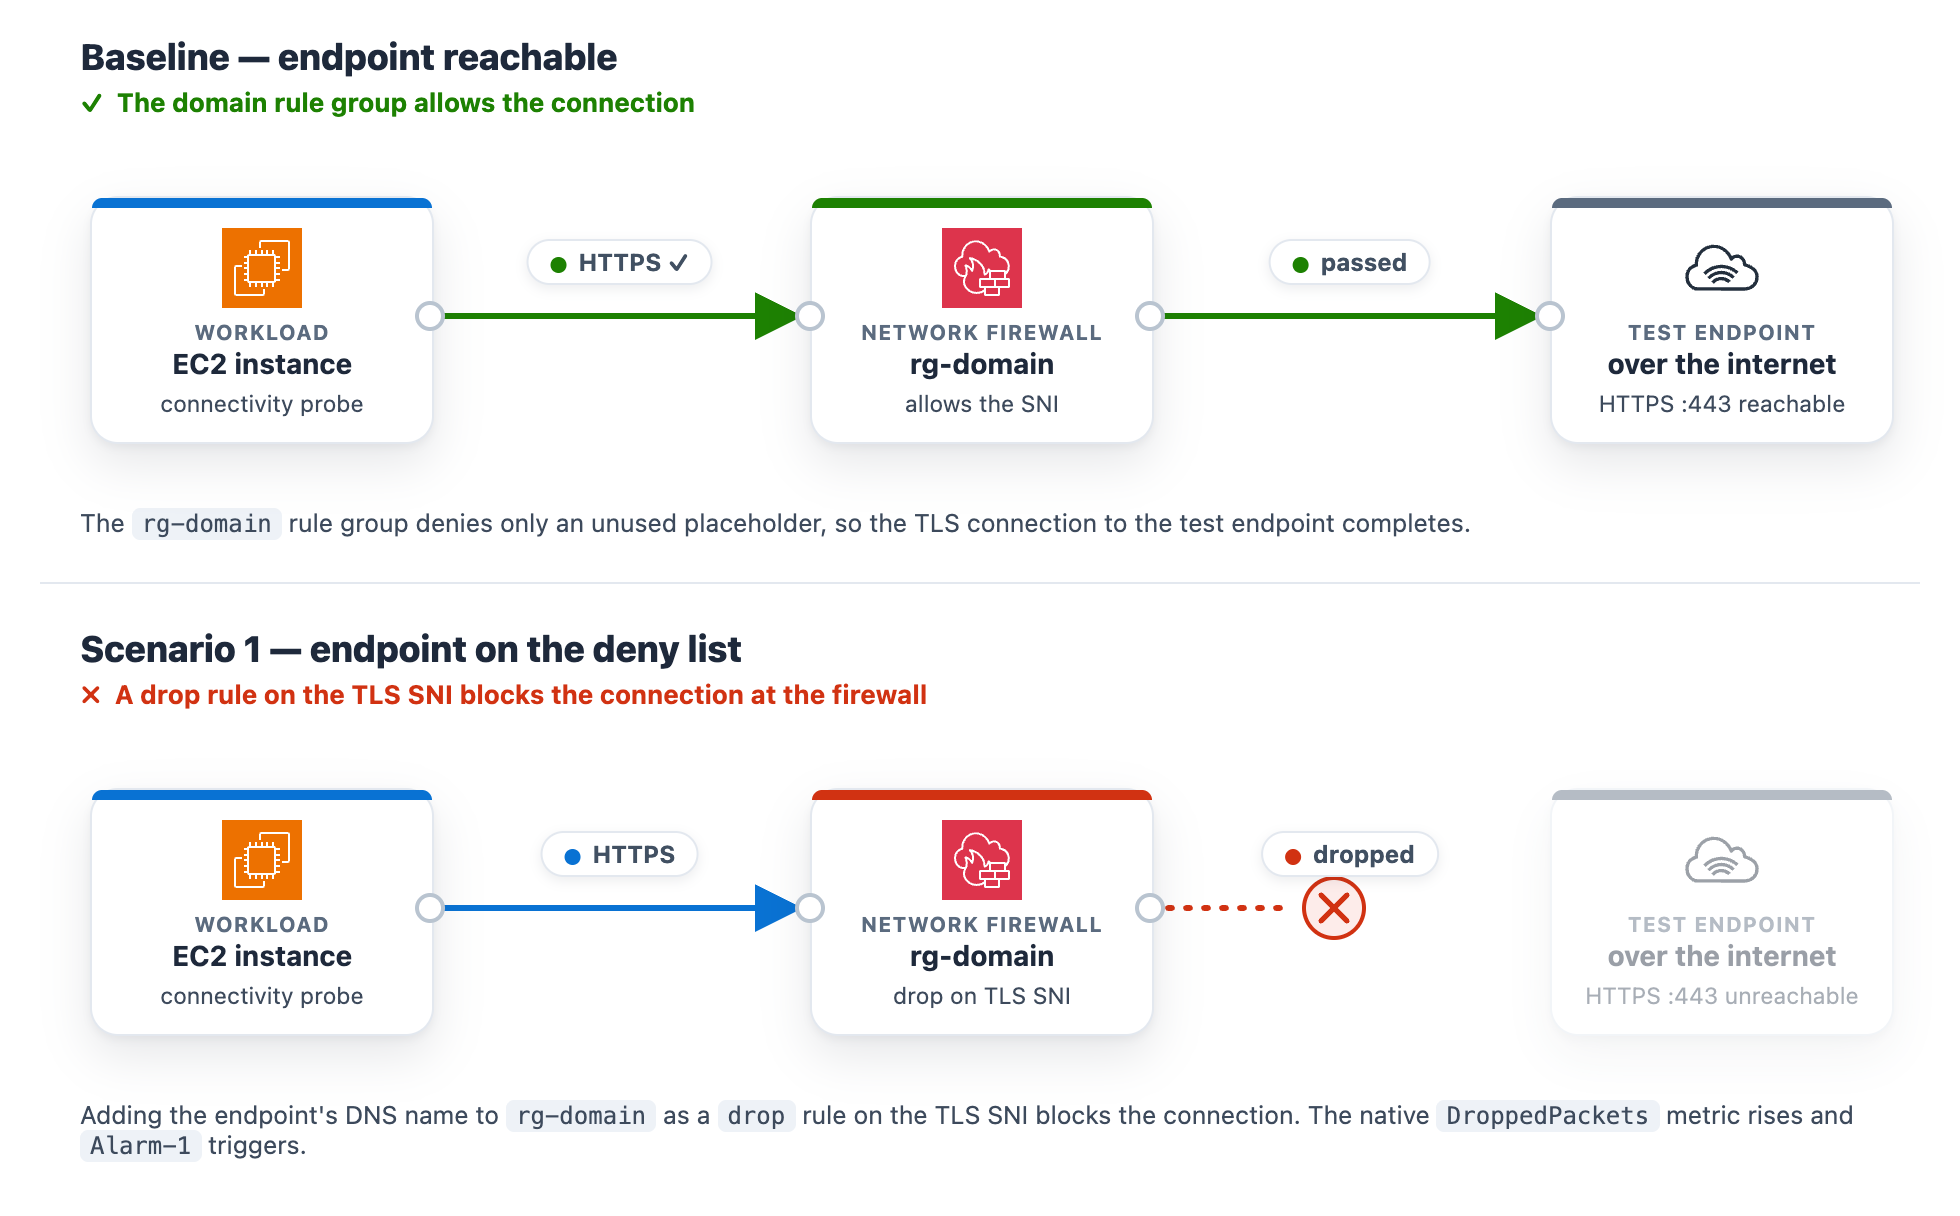
At baseline, the rg-domain Suricata domain rule group denies only an unused placeholder, so the test endpoint stays reachable. The rule group inspects the TLS Server Name Indication (SNI) on each outbound connection and drops any that matches a denied domain. The exact rule syntax and console steps follow.

To add the domain deny rule

  1. Go to the Amazon VPC console.
  2. In the navigation pane, under Network Firewall, choose Network Firewall rule groups.
  3. Choose the rg-domain rule group to open its details page.
  4. In the Rules section, choose Edit.
  5. The rules box already contains two baseline placeholder rules (they match blocked.placeholder.invalid, so nothing real is denied). Leave those in place. Find the <app-endpoint-dns> value for Scenario 1 in the deployment script output (a Nework Load Balancer (NLB) DNS name such as NfTest-AppNl-a1b2C3dEf4G5-1234abcd5678efgh.elb.us-east-1.amazonaws.com). On a new line below the existing rules, add a drop rule that matches that DNS name on the TLS SNI, then choose Save.
    drop tls $HOME_NET any -> $EXTERNAL_NET any (ssl_state:client_hello; tls.sni; content:"<app-endpoint-dns>"; startswith; nocase; endswith; msg:"S1 domain denylist"; flow:to_server, established; sid:2000002; rev:1;)

  6. After saving, the rules box holds all three lines. The two placeholders remain, plus the new drop rule for the endpoint DNS name (note the distinct sid 2000002).
Figure 2: Scenario 1 – Firewall rule change blocking the connection

Figure 2: Scenario 1 – Firewall rule change blocking the connection

What happens. The workload’s HTTPS check to the test endpoint times out, the “AWS/NetworkFirewall DroppedPackets metric climbs above baseline, and Alarm-1 moves to ALARM. The Scenario 1 card reads DROPPED (with the condition Firewall dropping the monitored domain on its allow/deny rules), while the Scenario 2 and Scenario 3 cards stay Healthy (Figure 3). On the topology, the alarm pipeline from CloudWatch through Amazon SNS and Lambda to DevOps Agent and the workload-to-firewall inspect lines both turn amber, which the legend defines as collateral / alarm active, because the packets are now dropped at the firewall. To demonstrate the resulting failure, the HTTPS · SNI line from the internet gateway to the test endpoint is shown in red, which the legend defines as dropped (root cause).

Figure 3: Scenario 1 active – Traffic blocked at the firewall

Figure 3: Scenario 1 active – Traffic blocked at the firewall

Let DevOps Agent investigate. The agent runs several lines of investigation in parallel and correlates them:

  1. Reads the DroppedPackets metric and correlates the spike with a simultaneous drop in passed packets, confirming the firewall is actively blocking traffic.
  2. Reads the ALERT log and finds the workload’s TLS connections to the test endpoint blocked by the S1 domain denylist rule.
  3. Compares the current state against a baseline window, where the same endpoint was reachable with no alerts, which shows the block is new.
  4. Searches CloudTrail and surfaces the UpdateRuleGroup call that added the deny rule, identifying the user, role, and timestamp approximately one minute before the drops began.
  5. Reports the root cause as that manual rule-group change. Recommends removing the deny entry or adding an allow exception and enabling FirewallPolicyChangeProtection to prevent unauthorized changes.
  6. Presents this as a plan you review and apply, not an automatic change.

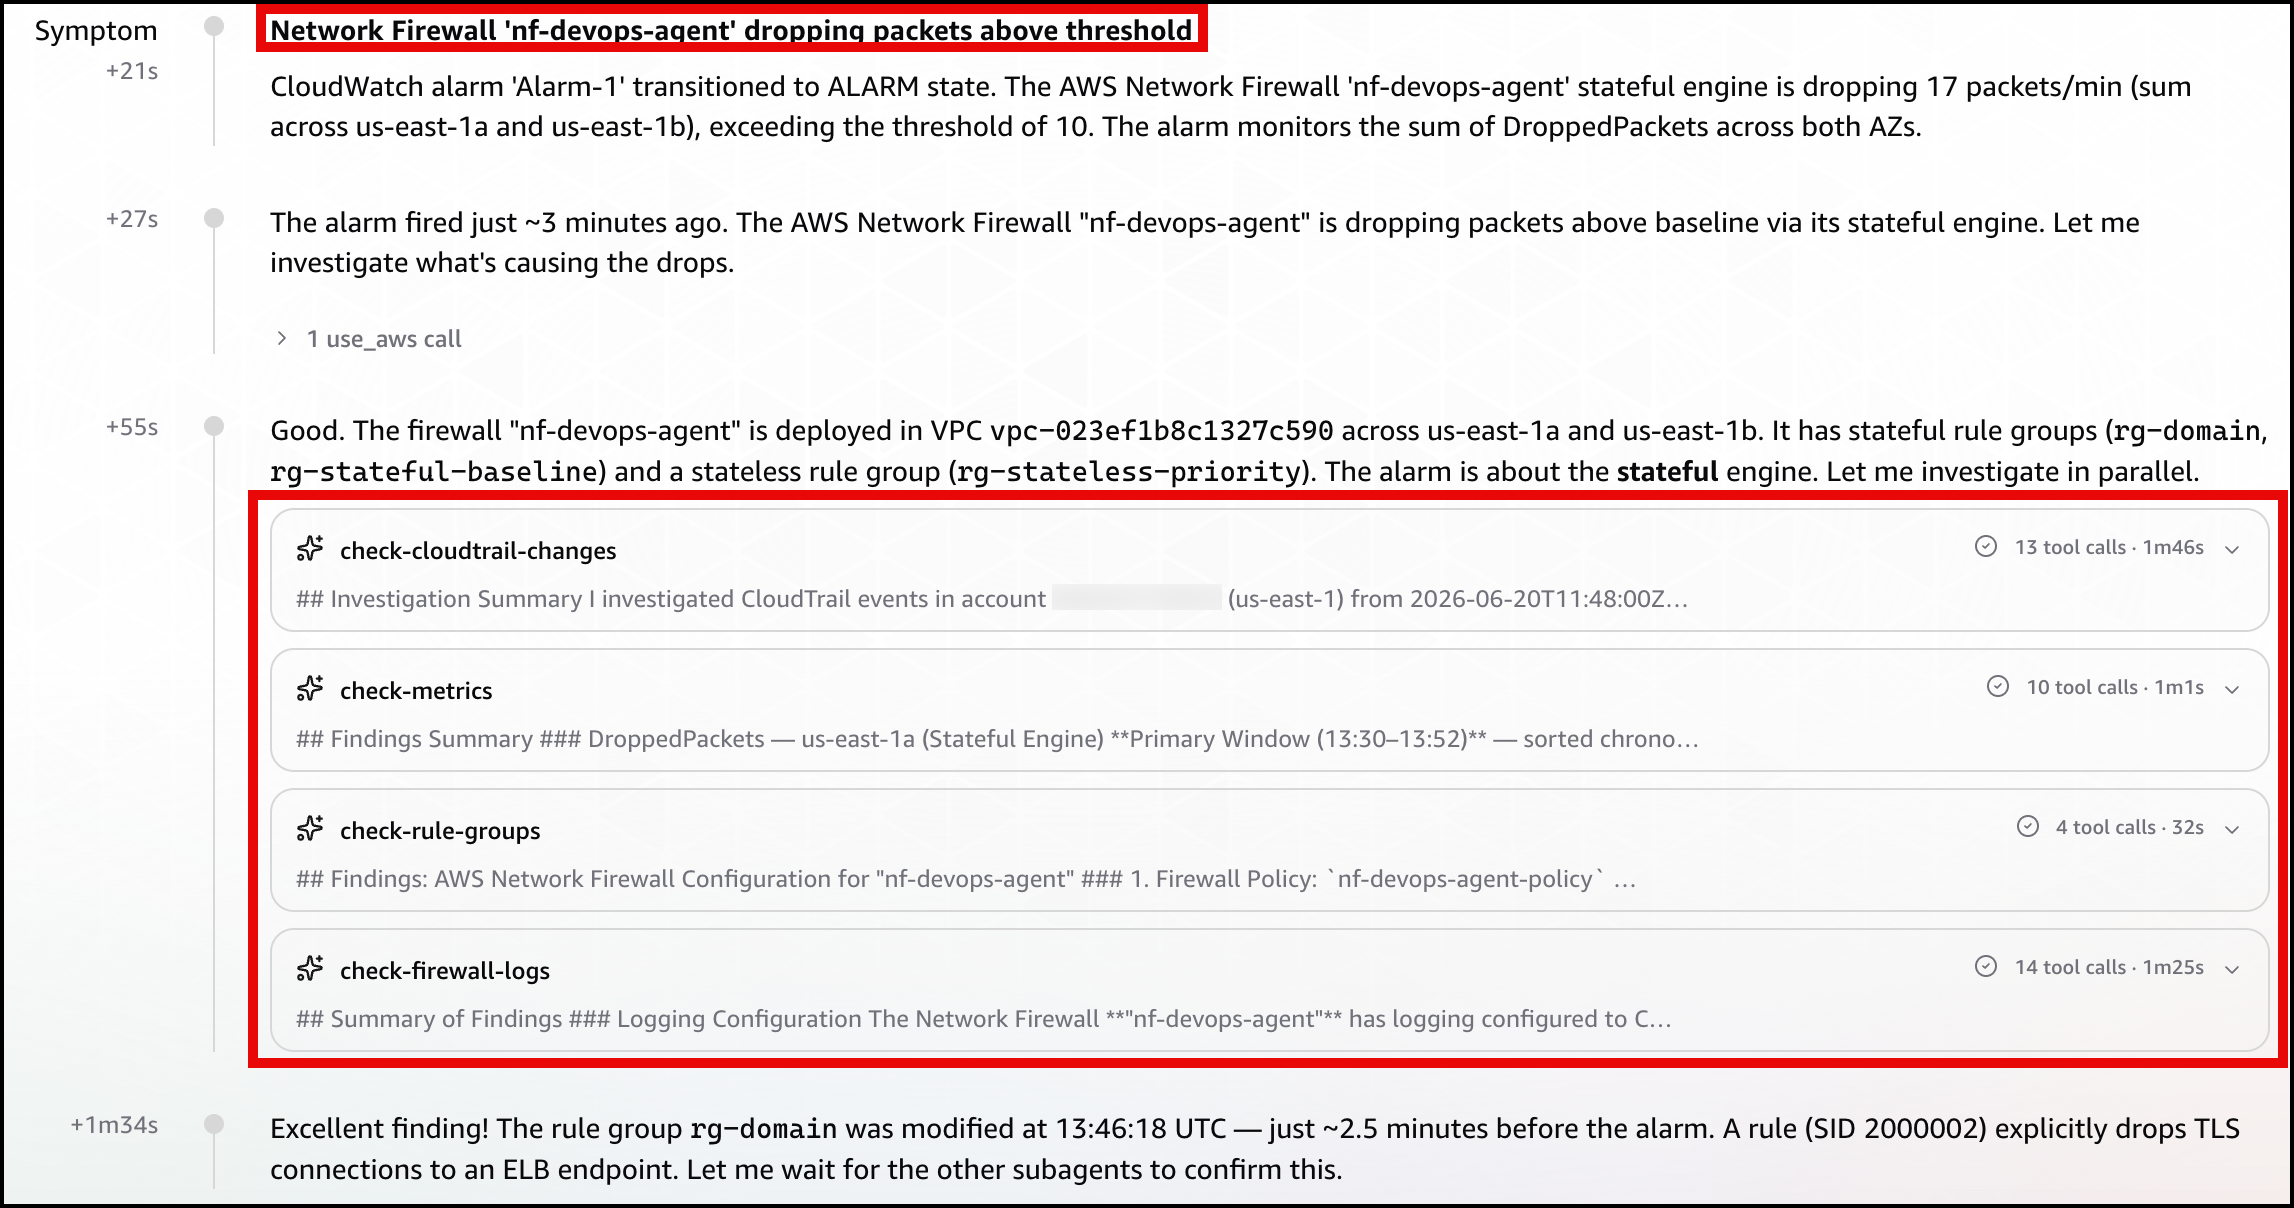
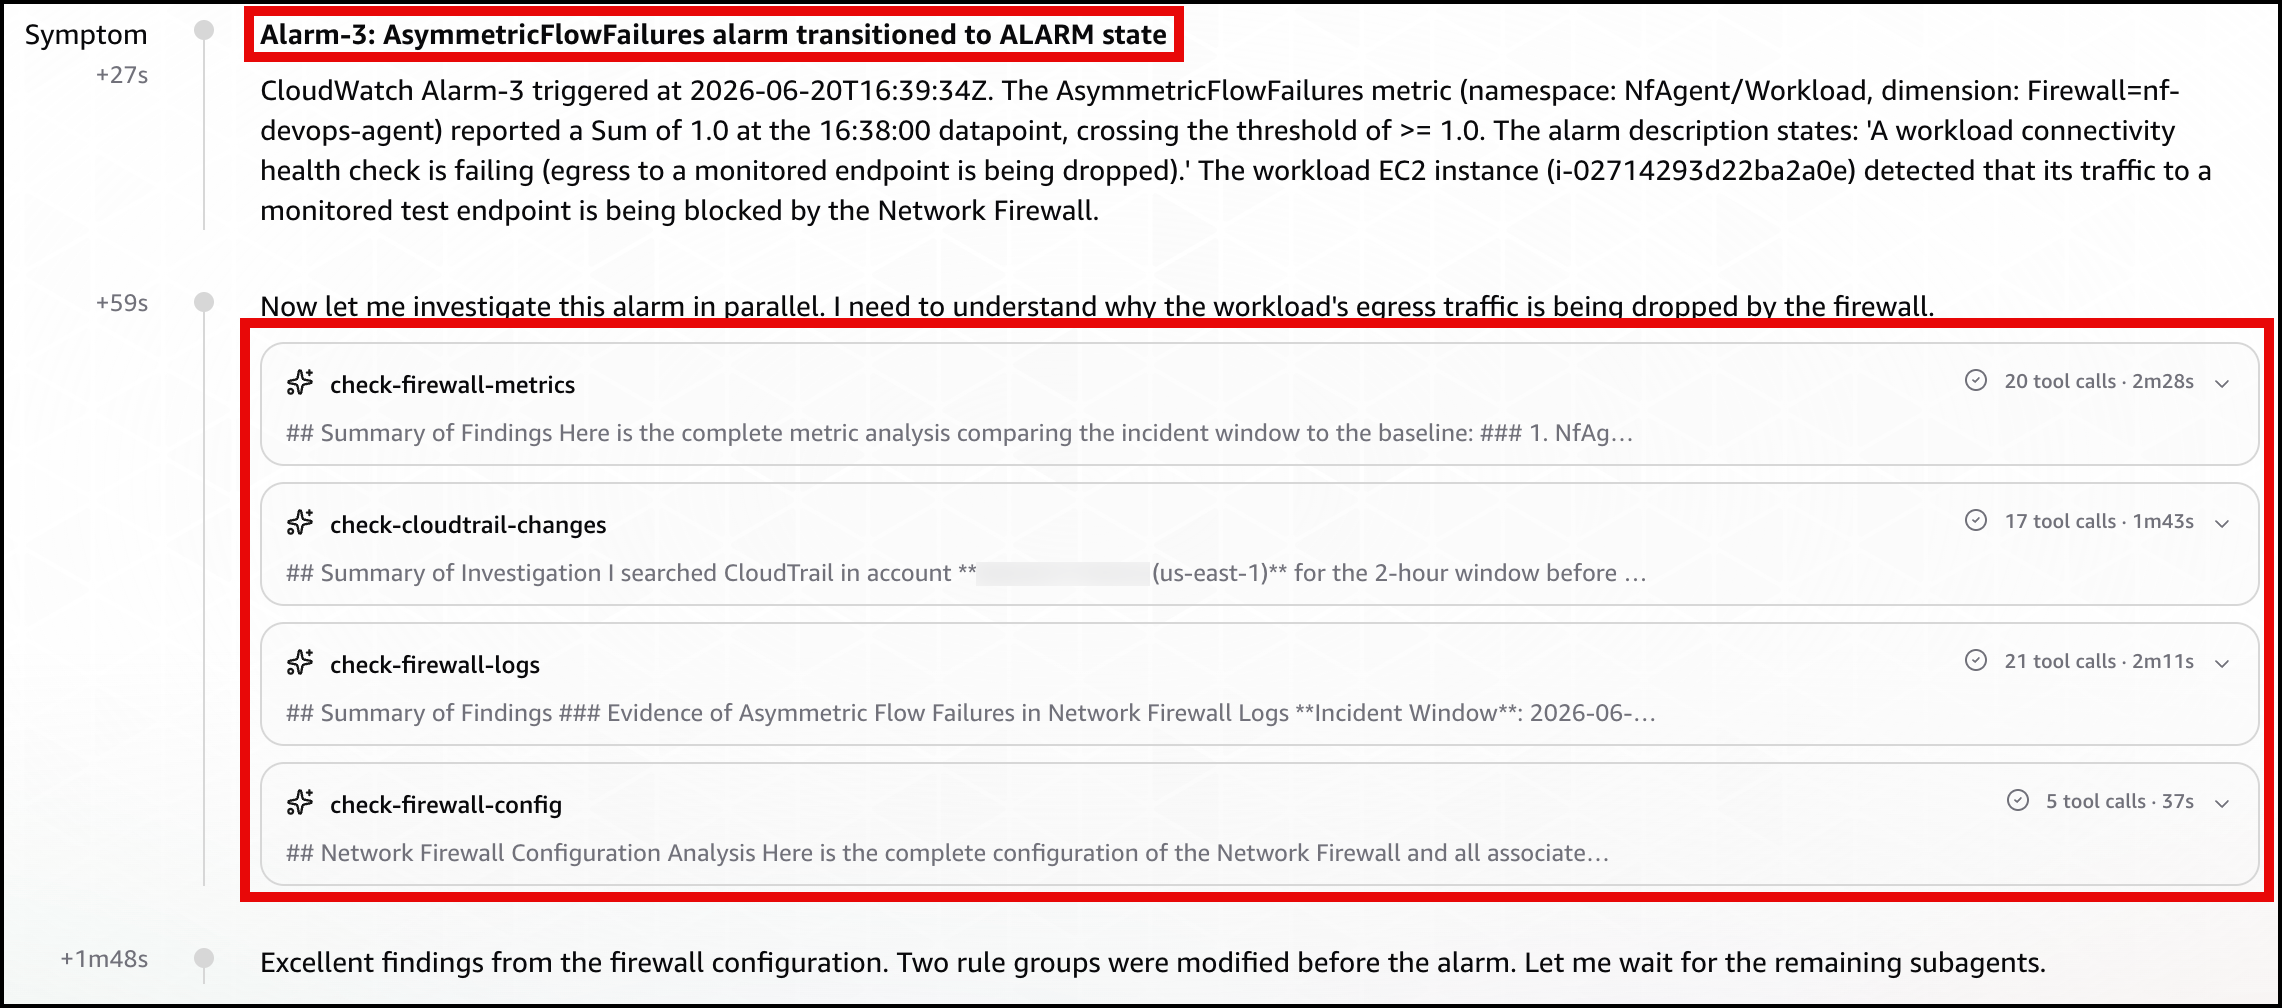
In the DevOps Agent Operator Web App view, the agent first restates the Alarm-1 trigger and confirms the firewall is dropping packets above the threshold (Figure 4).

Figure 4: Scenario 1 – The symptom

Figure 4: Scenario 1 – The symptom

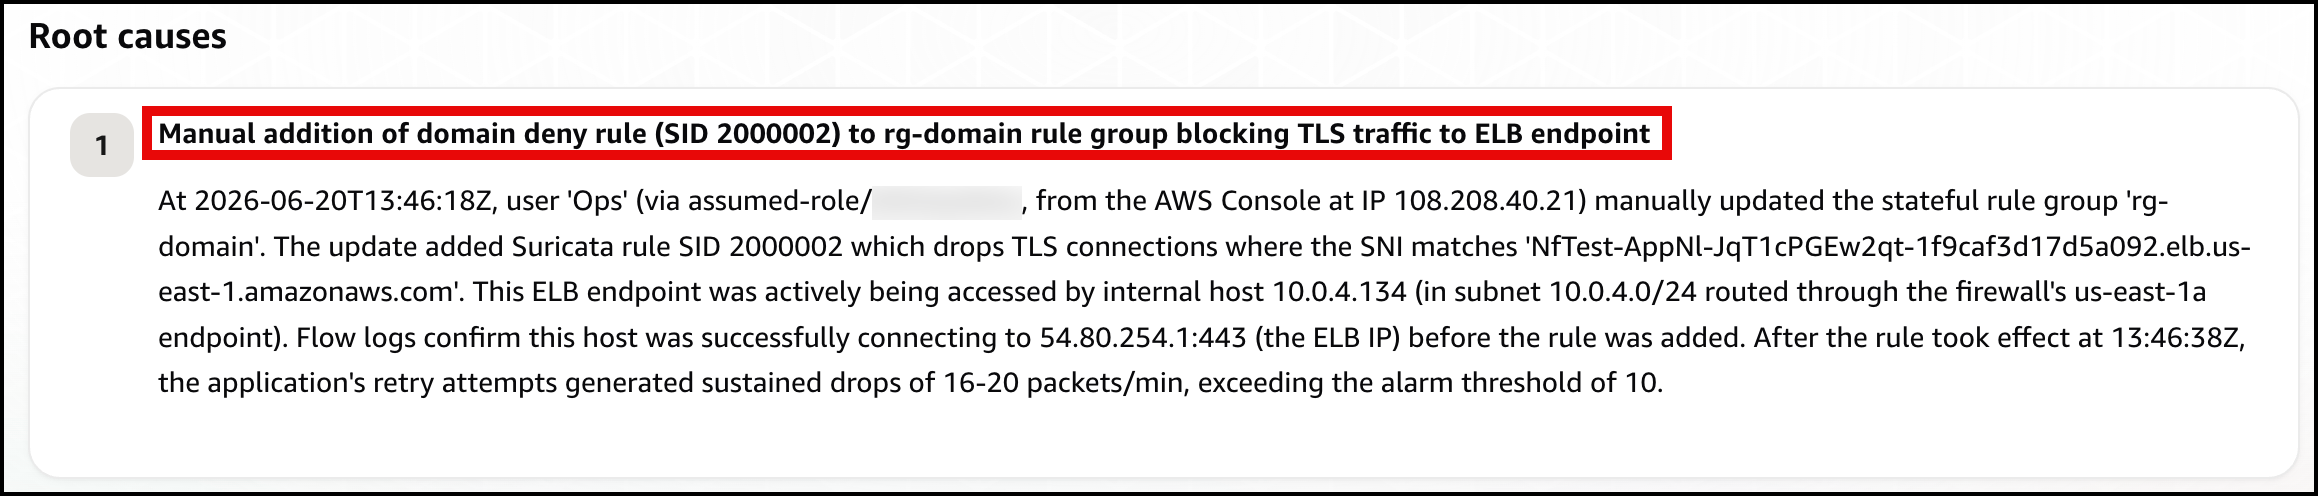
Next, the agent identifies the root cause: a manual update to the rg-domain rule group that added a domain deny rule (SID 2000002) shortly before the alarm fired, blocking TLS connections to the ELB endpoint (Figure 5).

Figure 5: Scenario 1 – The root cause

Figure 5: Scenario 1 – The root cause

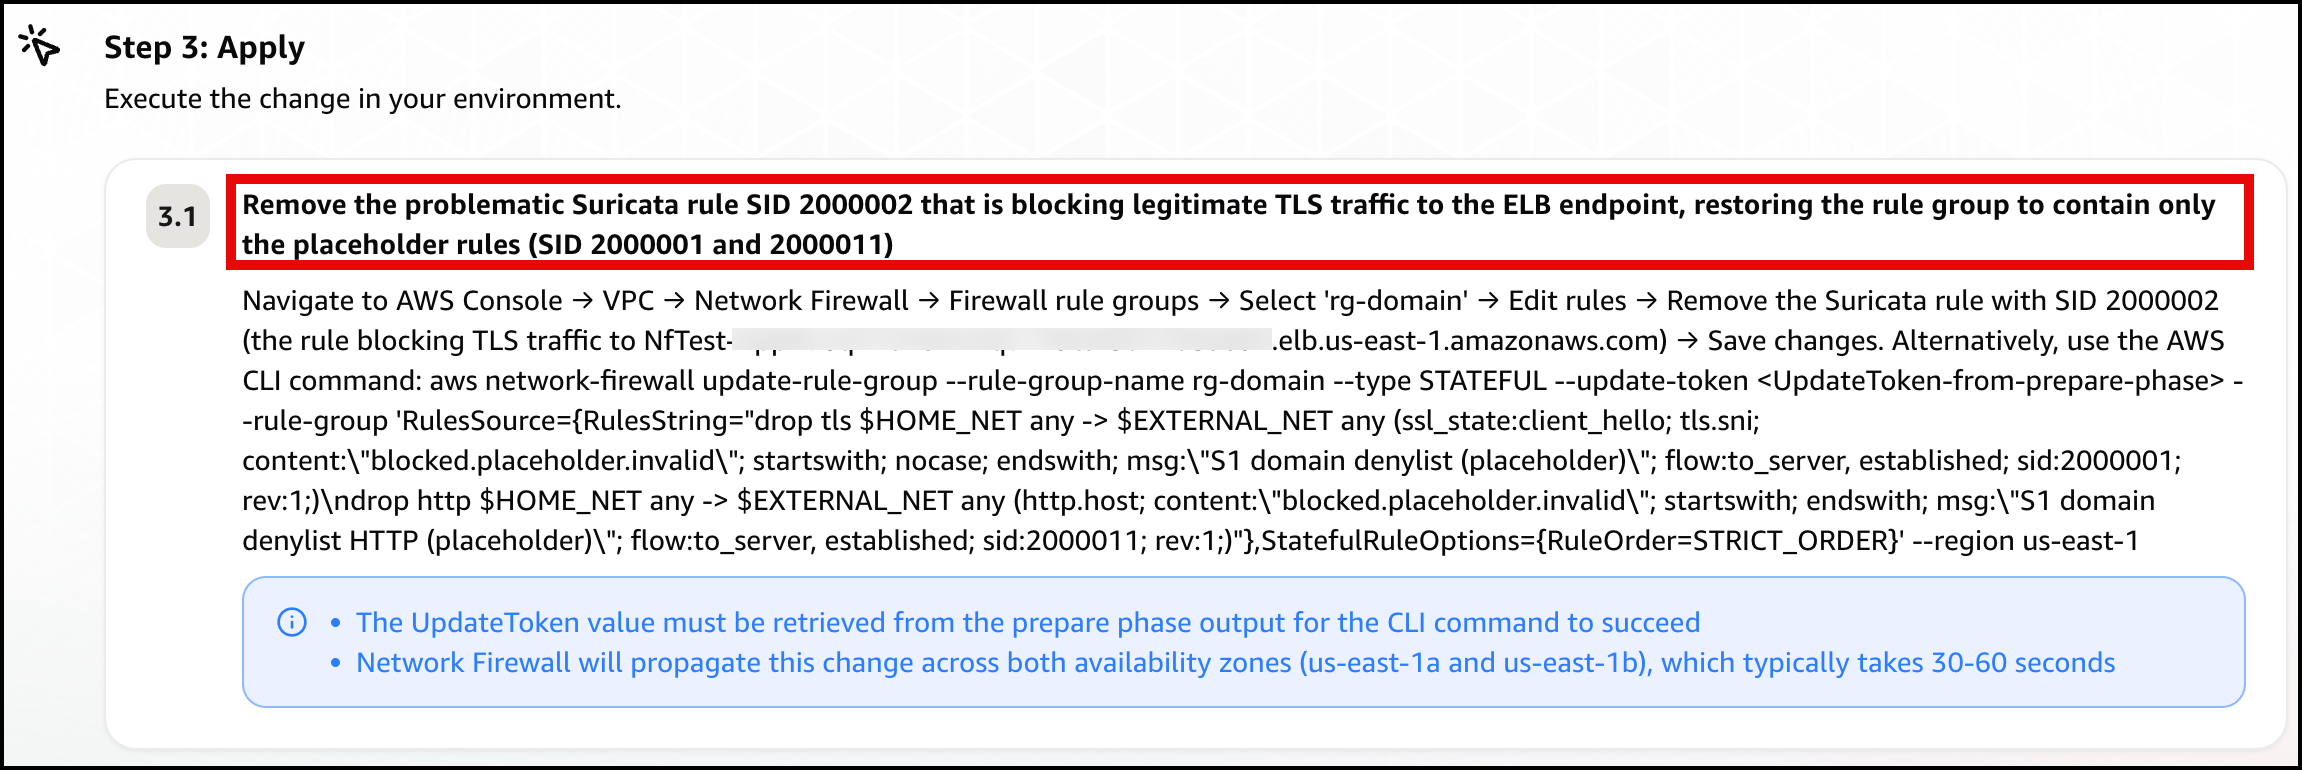
Finally, the agent presents a mitigation plan, recommending you remove the problematic deny rule (SID 2000002) to restore connectivity (Figure 6).

Figure 6: Scenario 1 – The mitigation plan

Figure 6: Scenario 1 – The mitigation plan

Note: In a real-world environment, this type of rule typically exists for a reason. Before removing it, verify whether it was intentional but scoped too broadly. If so, refine the rule to block only unauthorized endpoints rather than removing it entirely.

Confirm recovery. Apply the change the agent recommends. After the deny entry is gone, DroppedPackets falls back to baseline, Alarm-1 clears, and the card returns to green. Move on to Scenario 2.

Scenario 2. Stateless rule priority misconfiguration

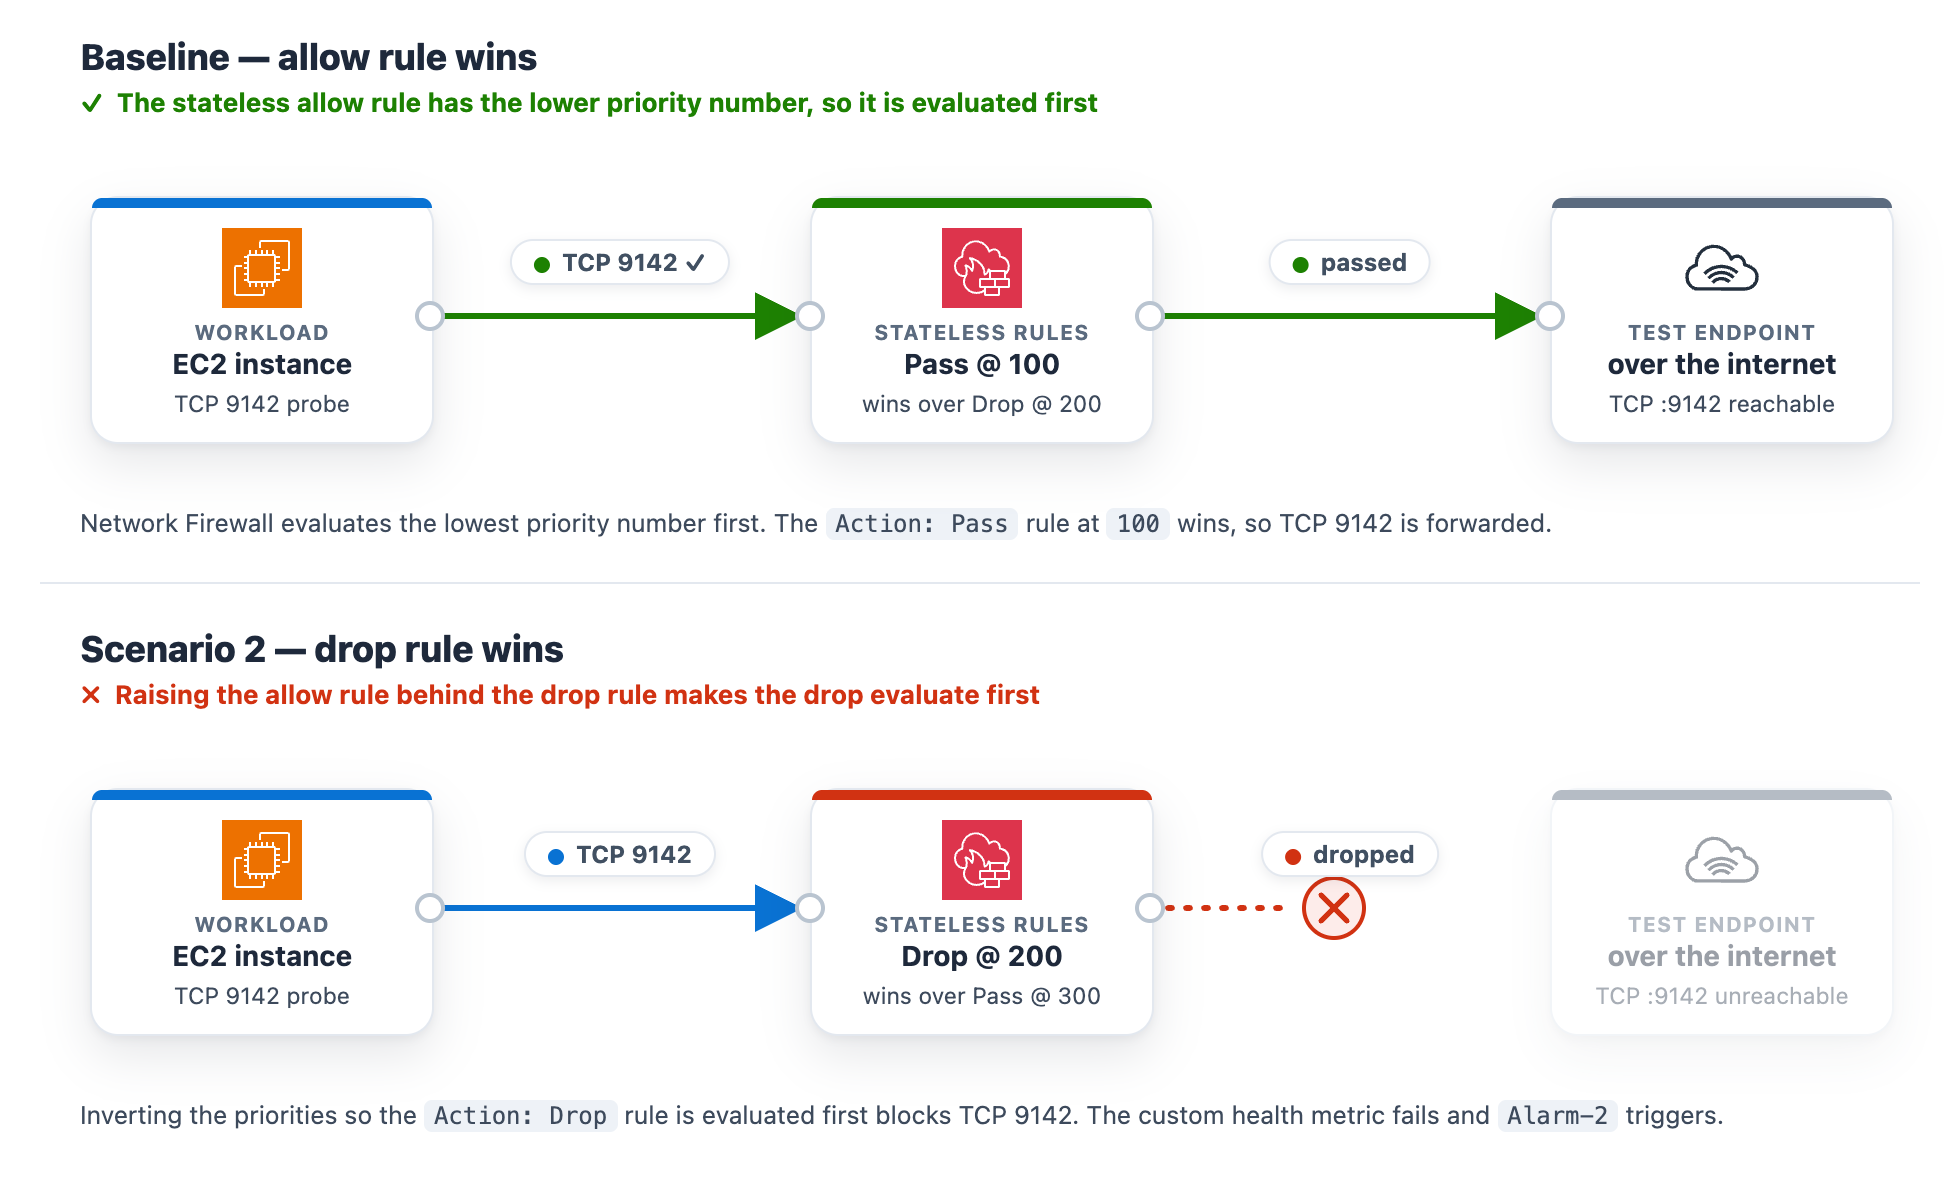
At baseline, the rg-stateless-priority stateless rule group keeps the allow rule at priority 100 and the drop rule at 200 for the test class, TCP destination port 9142. The workload opens a TCP connection to the test endpoint on this port. Lower priority numbers evaluate first, so the allow rule wins. This scenario uses port 9142 instead of 443 to demonstrate a stateless rule, which matches on the packet’s 5-tuple (protocol, ports, addresses) rather than application content.

Introduce the change. Invert the two rule priorities so the drop rule evaluates before the allow rule. This is the kind of change a rushed rule edit can introduce.

To invert the stateless rule priorities

  1. Go to the Amazon VPC console.
  2. In the navigation pane, under Network Firewall, choose Network Firewall rule groups.
  3. Choose the rg-stateless-priority rule group to open its details page.
  4. In the Rules section, choose Edit.
  5. Raise the (Action: Pass) rule’s priority number so it sits after the (Action: Drop) rule, then choose Save. For example, change the (Action: Pass) rule from 100 to 300 (any number higher than the drop rule’s 200 works). You only need to move one rule, and using 300 avoids a clash with the drop rule that already sits at 200. Network Firewall evaluates the lowest priority number first, so the (Action: Drop) rule at 200 now wins for this traffic class, ahead of the (Action: Pass) rule at 300.
Figure 7: Scenario 2 – Rule priority change blocking the traffic class

Figure 7: Scenario 2 – Rule priority change blocking the traffic class

What happens. The drop rule now wins, the TCP connection to the test endpoint on port 9142 times out, the StatelessRuleFailures metric climbs above baseline, and Alarm-2 moves to ALARM. The Scenario 2 card reads DROPPED (with the condition Stateless rules dropping the monitored traffic class), while the Scenario 1 and Scenario 3 cards stay Healthy (Figure 8). On the topology, the alarm pipeline from CloudWatch through Amazon SNS and Lambda to DevOps Agent and the workload-to-firewall inspect lines both turn amber, which the legend defines as collateral / alarm active, because the packets are now dropped at the firewall. To demonstrate the resulting failure, the TLS :9142 line from the internet gateway to the test endpoint is shown in red, which the legend defines as dropped (root cause).

Figure 8: Scenario 2 active

Figure 8: Scenario 2 active

Let DevOps Agent investigate. A stateless drop happens before traffic reaches the stateful inspection engine, so it produces no ALERT log entries. The agent turns to configuration and flow logs instead:

  1. Reads the stateless rule group state and finds the drop rule at the lower priority number, ahead of the pass rule, so the drop evaluates first.
  2. Reads the flow logs and sees passed packets drop to zero within a minute of the change.
  3. Searches CloudTrail and surfaces the UpdateRuleGroup call that inverted the priorities, identifying the user, role, and timestamp about a minute before the alarm.
  4. Reports the root cause as that priority inversion. Recommends removing the redundant drop rule and managing the rule group through infrastructure-as-code (IaC) to prevent manual misconfigurations.
  5. Presents this as a plan you review and apply, not an automatic change.

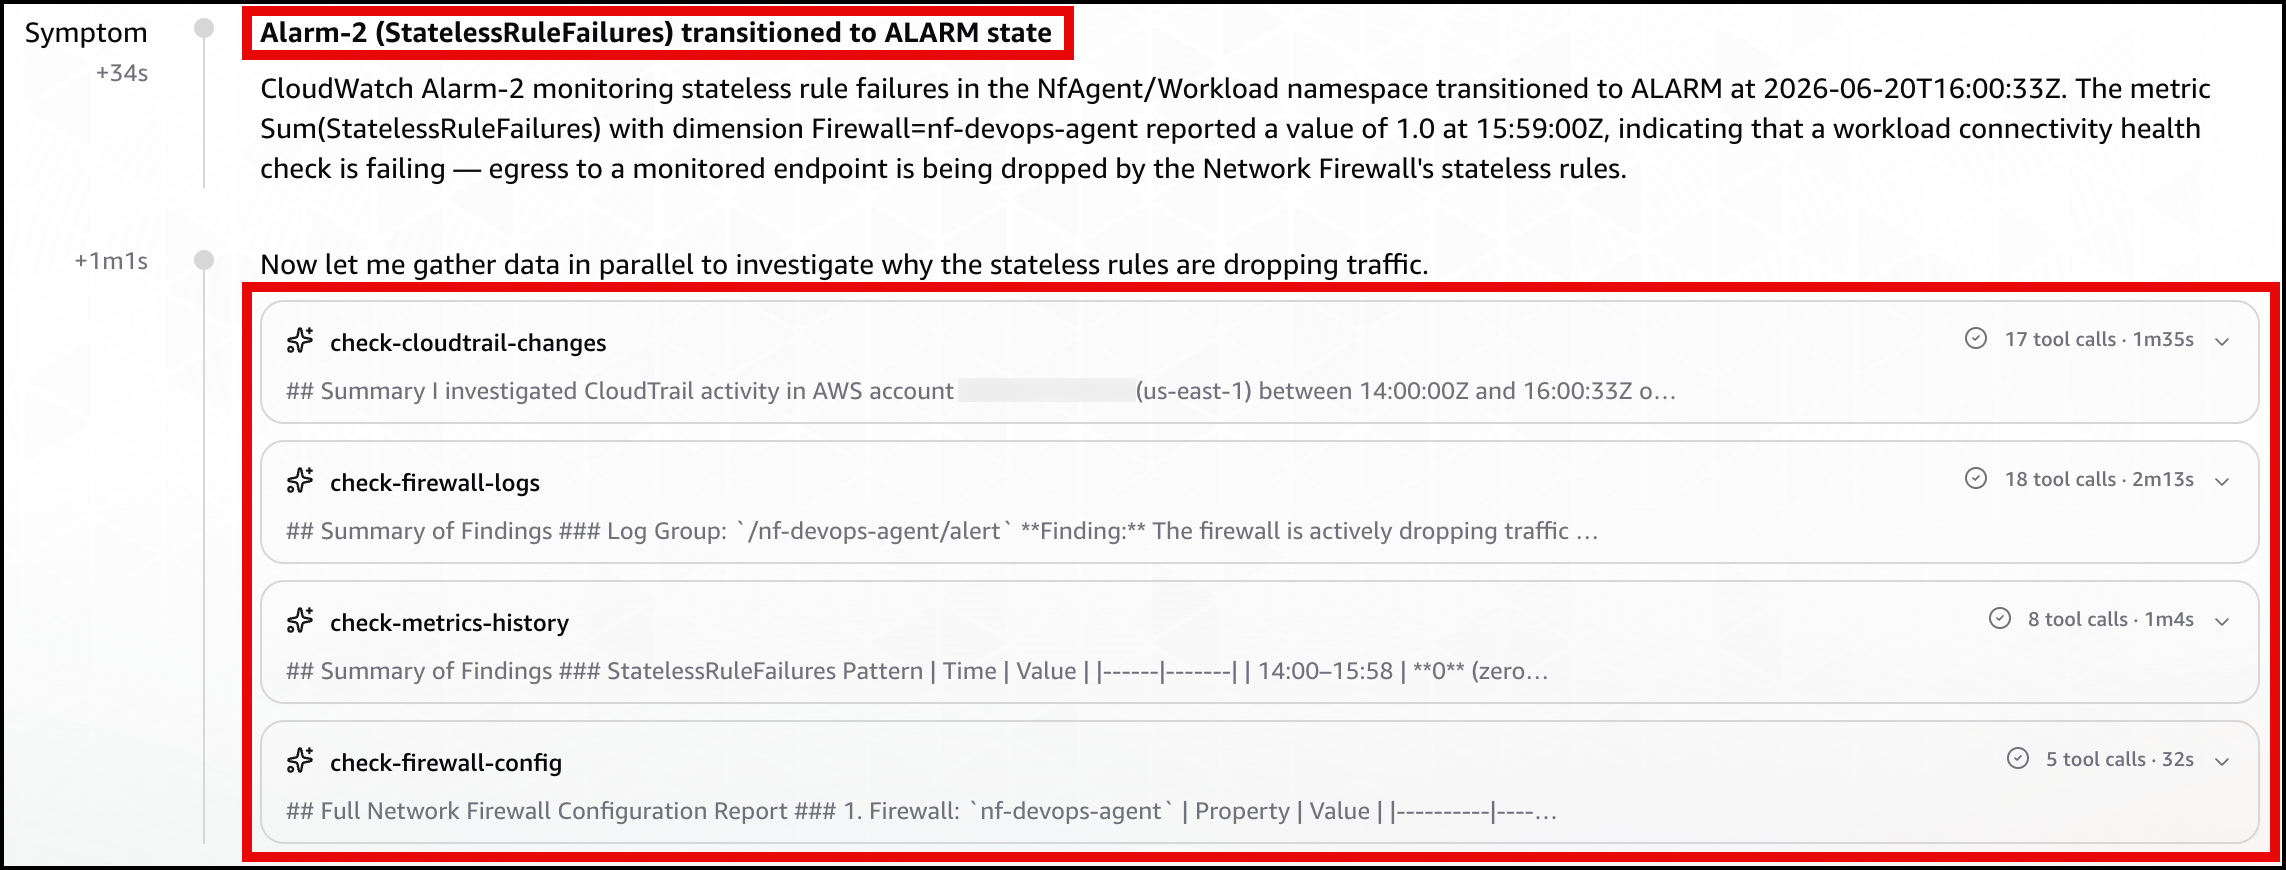
In the DevOps Agent Operator Web App view, the agent first restates the Alarm-2 trigger and confirms that a workload connectivity health check is failing because the firewall’s stateless rules are dropping egress (Figure 9).

Figure 9: Scenario 2 – The symptom

Figure 9: Scenario 2 – The symptom

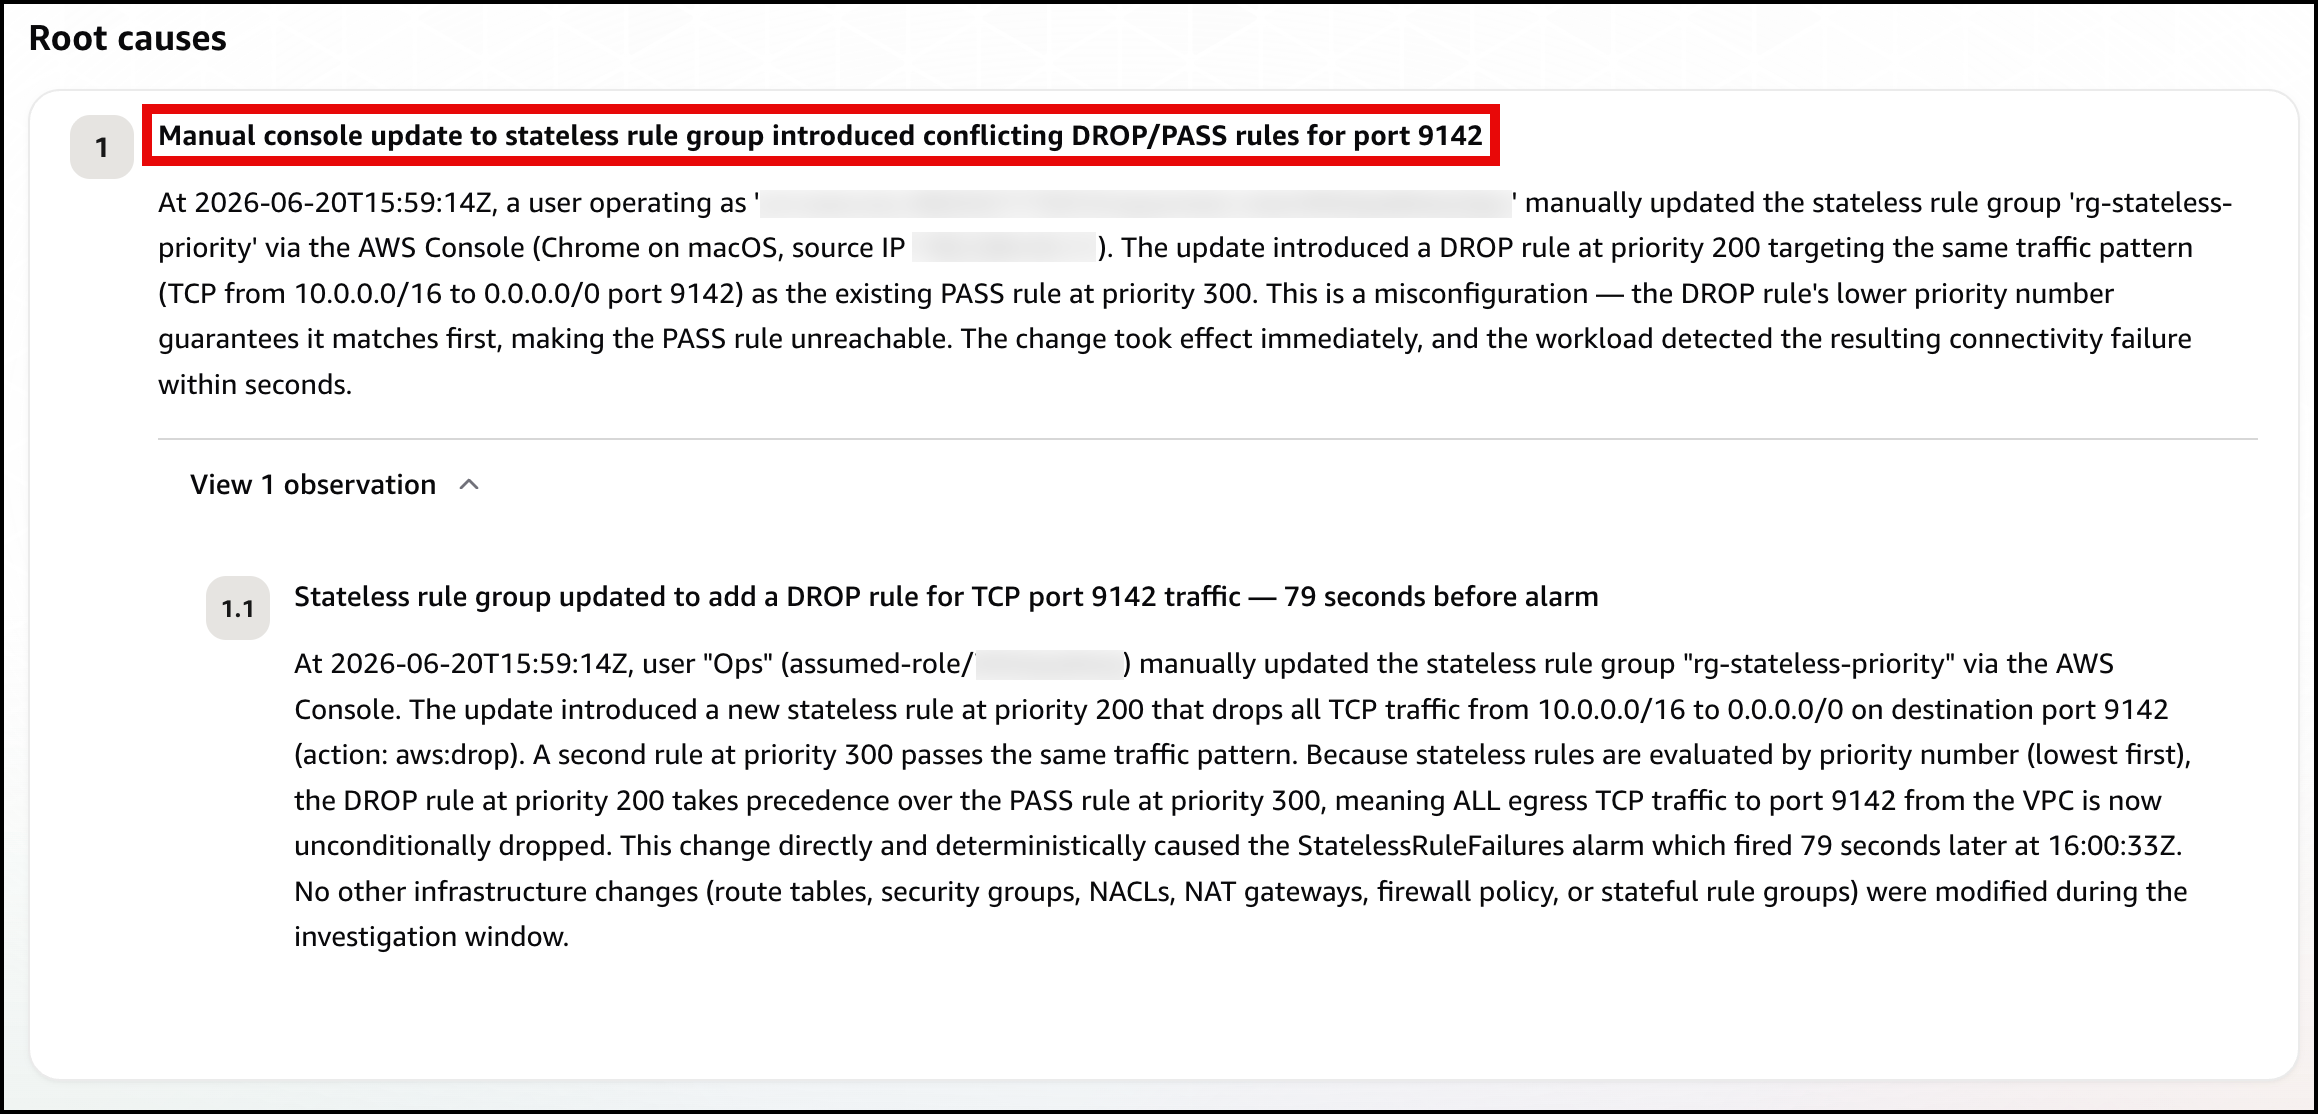
Next, the agent identifies the root cause, using the rule-group state and CloudTrail to pinpoint the conflicting DROP/PASS rules, where the new DROP rule’s lower priority number makes it match first (Figure 10).

Figure 10: Scenario 2 – The root cause

Figure 10: Scenario 2 – The root cause

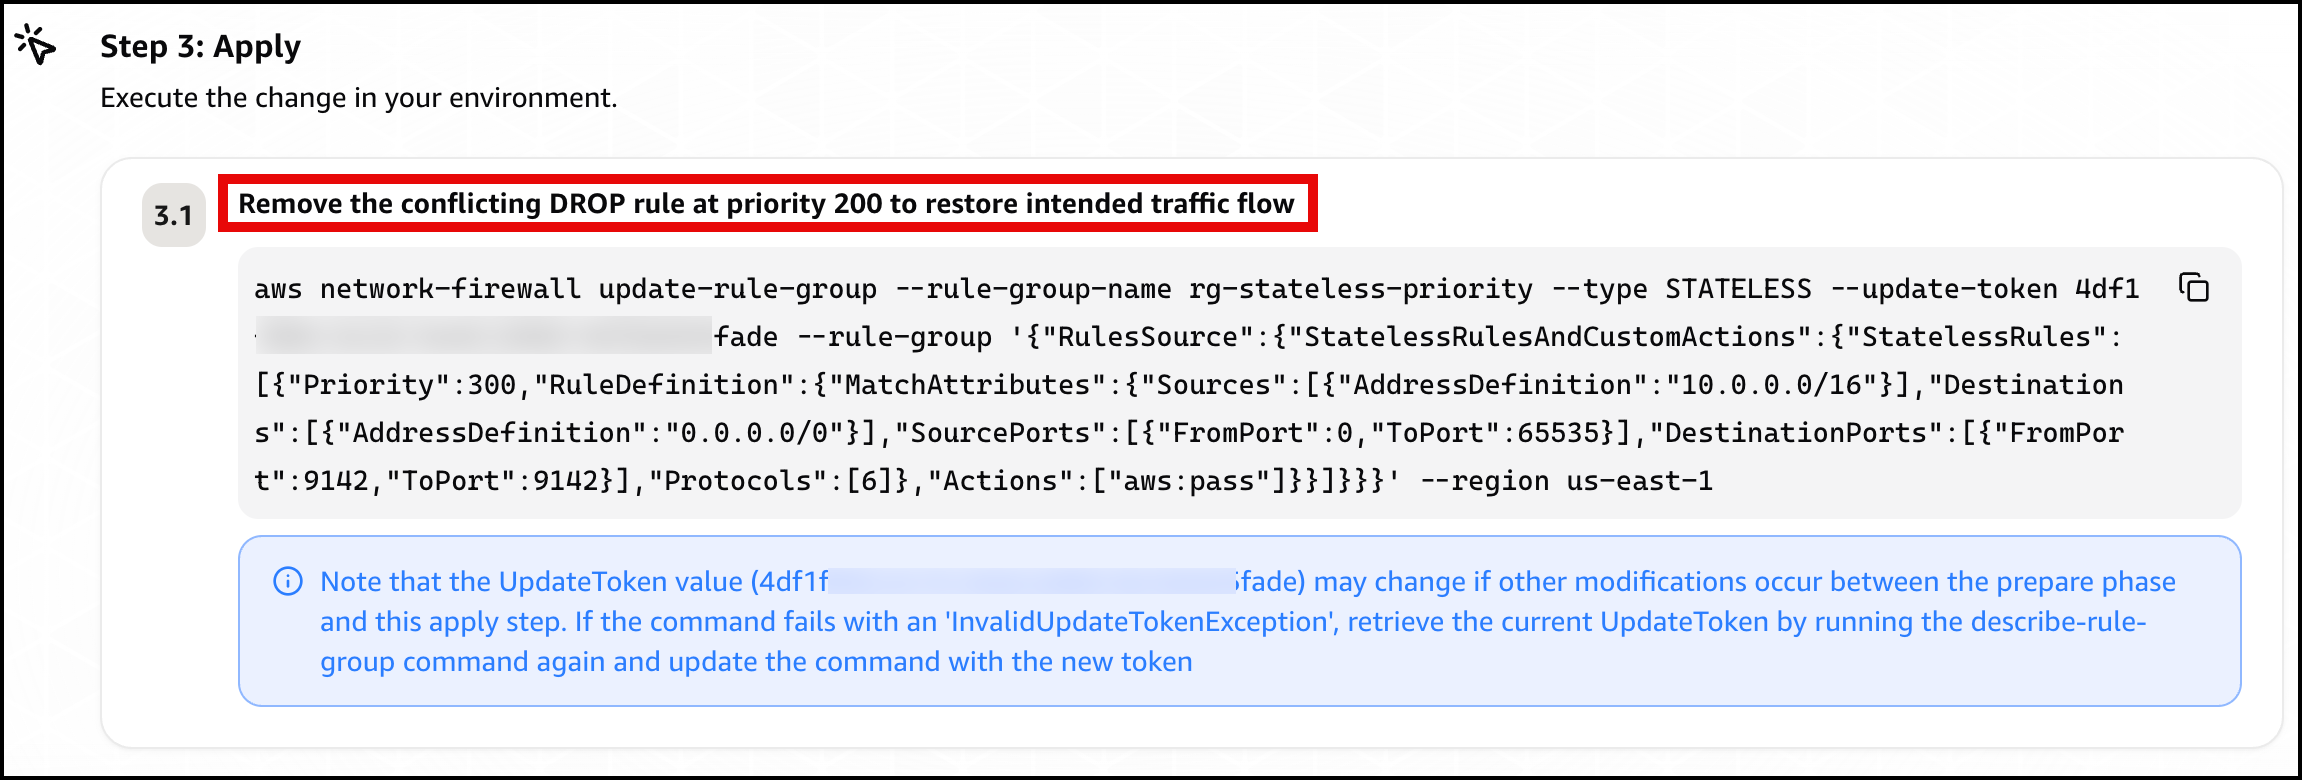
Finally, the agent presents a mitigation plan, recommending you remove the conflicting DROP rule at priority 200 to restore traffic flow (Figure 11).

Figure 11: Scenario 2 – The mitigation plan

Figure 11: Scenario 2 – The mitigation plan

Confirm recovery. Apply the change the agent recommends. After the allow rule is ahead of the drop rule again, Alarm-2 clears and the card returns to green. Move on to Scenario 3.

Scenario 3. Asymmetric cross Availability Zone routing drop

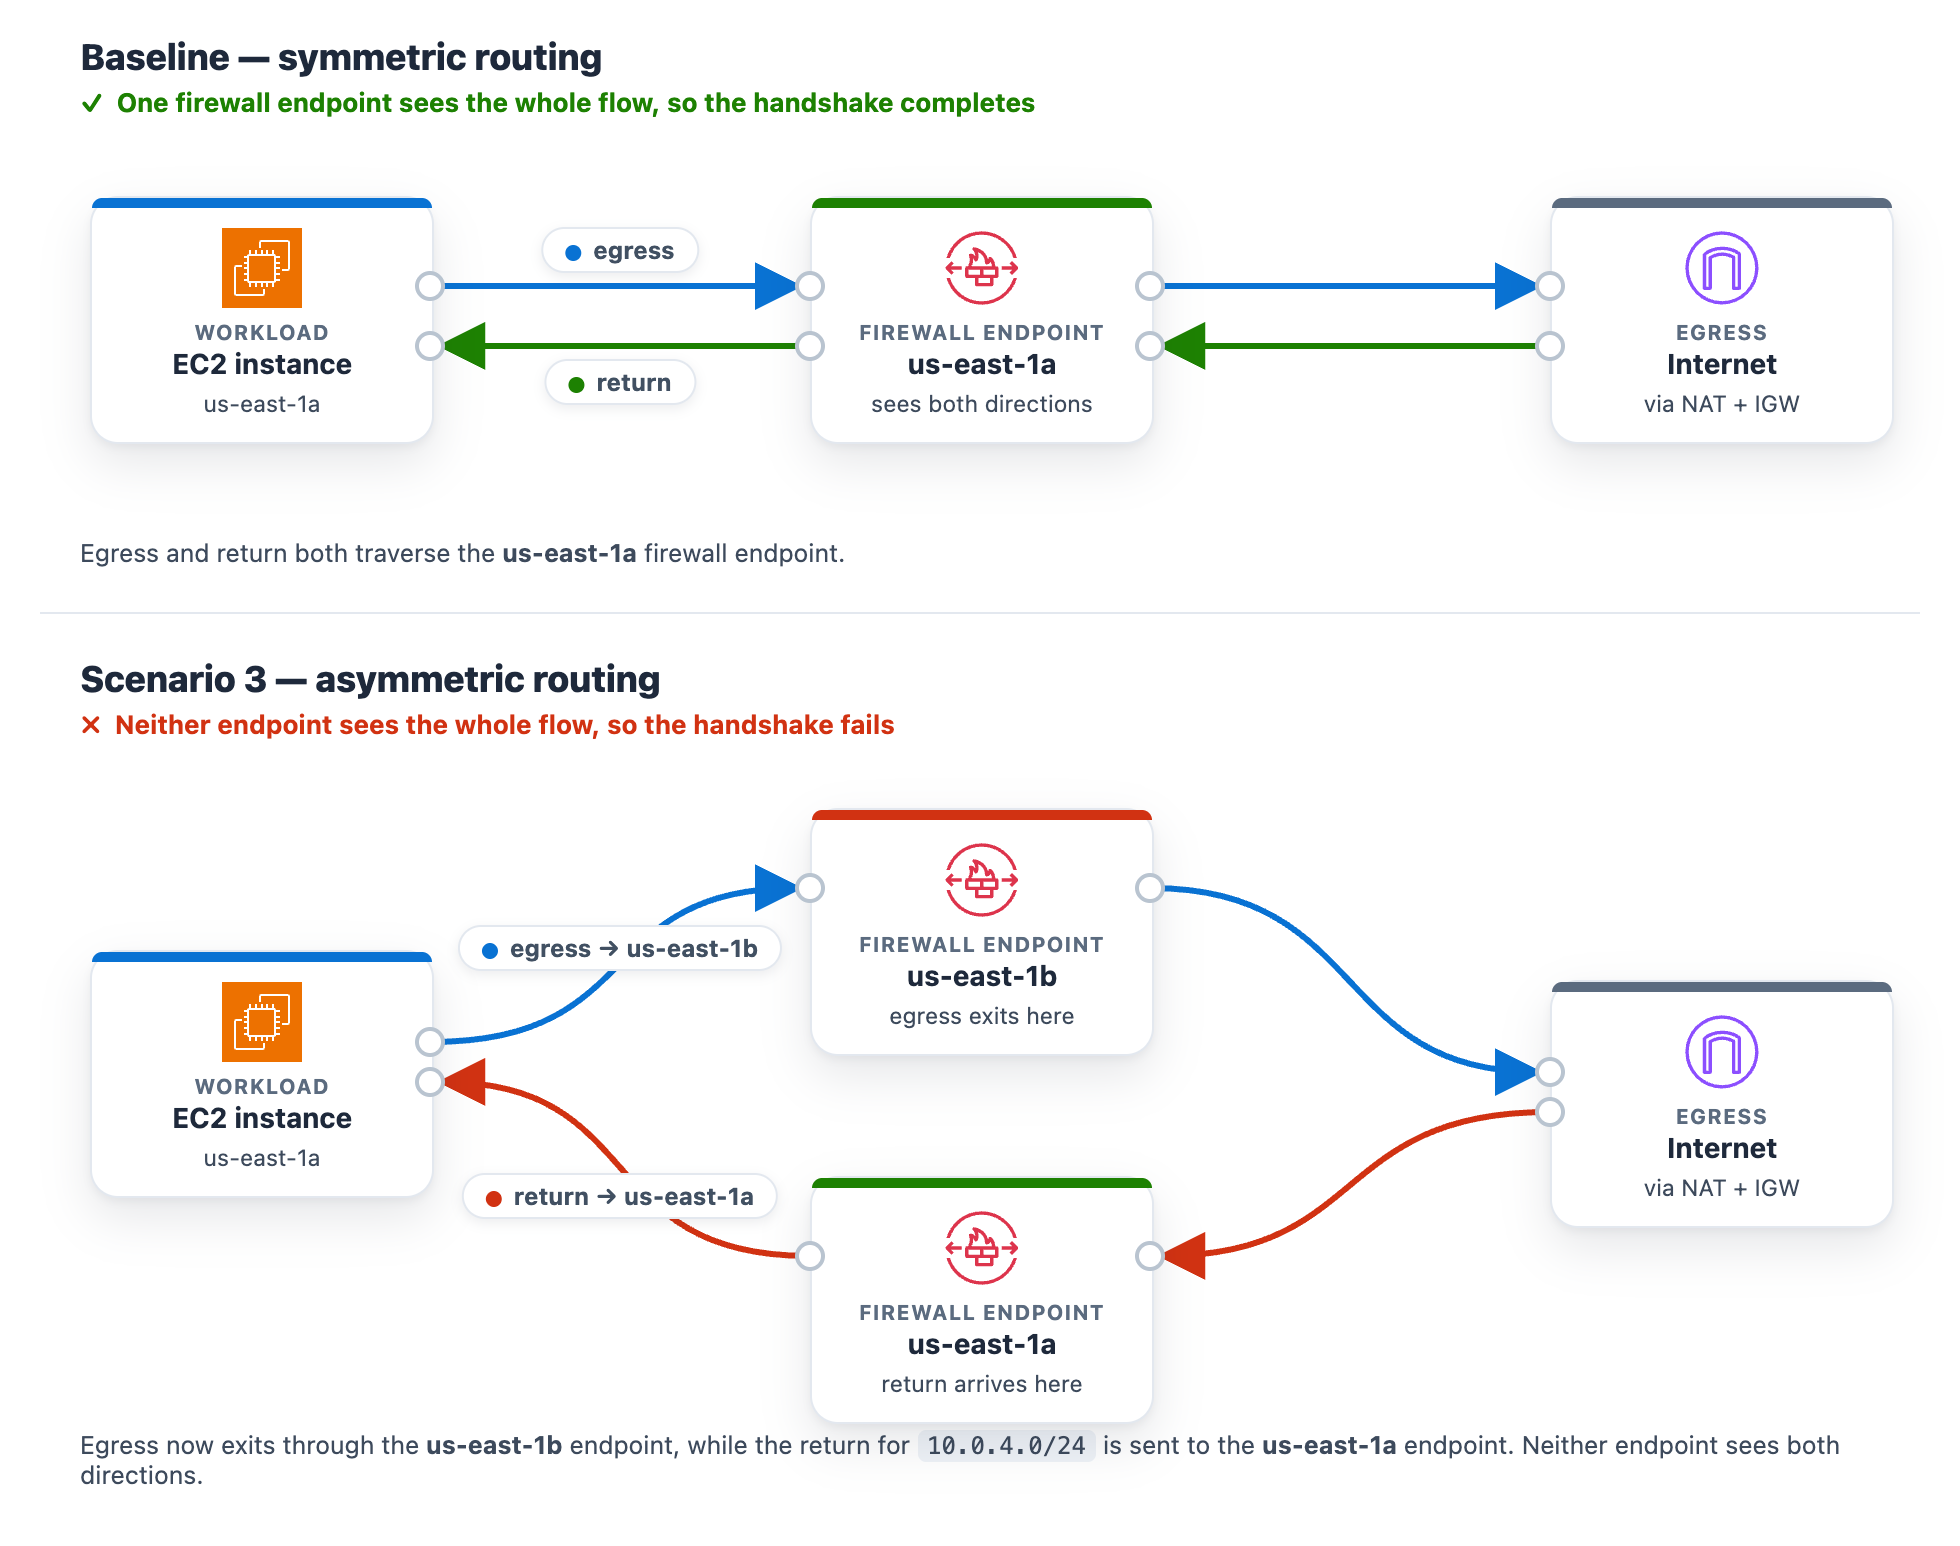
At baseline, the protected subnet in each Availability Zone routes its egress through the firewall endpoint in that same Availability Zone , and the matching return route uses that same endpoint. One endpoint sees both directions of the flow, so the stateful engine completes the handshake. The workload runs in the protected subnet in us-east-1a (CIDR 10.0.4.0/24), so at baseline its egress and its return both use the us-east-1a firewall endpoint.

Introduce the change. Make the flow asymmetric by sending egress out one Availability Zone endpoint while the return comes back through the other. This takes two route edits, and both are required. With only the first edit the flow can still complete, so the alarm will not trigger until both are saved. It makes no firewall-policy change, mirroring a real multi-Availability-Zone routing mistake.

To create asymmetric cross Availability Zone routing

  1. Go to the Amazon VPC console and choose Route tables in the navigation pane.
  2. Flip the egress. Select the NfNetworkStack/SampleVpc/protectedSubnet1 route table (the us-east-1a protected subnet, where the workload runs). On the Routes tab, choose Edit routes. Its 0.0.0.0/0 route currently targets the us-east-1a firewall endpoint. For the target, choose Gateway Load Balancer Endpoint and select the us-east-1b firewall endpoint, then choose Save changes.
  3. Move the return. Select the NfNetworkStack/SampleVpc/publicSubnet2 route table (the us-east-1b public subnet, where egress now exits). Choose Edit routes, then Add route. For the destination enter the workload CIDR 10.0.4.0/24. For the target, choose Gateway Load Balancer Endpoint and select the us-east-1a firewall endpoint. Choose Save changes.

After both edits, a flow’s egress leaves through the us-east-1b endpoint while its return is directed to the us-east-1a endpoint. Neither endpoint sees the whole flow.

Figure 12: Scenario 3 routing change breaking the flow’s symmetry

Figure 12: Scenario 3 routing change breaking the flow’s symmetry

What happens. A new connection leaves through one endpoint. Its return arrives at the other endpoint, which never saw the connection open, so the handshake fails. Unlike Scenarios 1 and 2, this affects the whole subnet, so all egress stops and Alarm-2 and Alarm-3 both move to ALARM. The AWS/NetworkFirewall DroppedPackets alarm (Alarm-1) stays quiet because no endpoint is making a drop decision. The flow is lost to asymmetric routing rather than counted as a firewall drop. This is why monitoring application connectivity matters. A routing fault is invisible to the firewall’s own drop counter. On the status page, the Scenario 2 card reads DROPPED (with the condition “Stateless rules dropping the monitored traffic class”) and the Scenario 3 card reads DROPPED (with the condition Return traffic dropped by asymmetric cross-Availability-Zone routing), while the Scenario 1 card stays Healthy (Figure 13). On the topology, the alarm pipeline from CloudWatch through Amazon SNS and Lambda to DevOps Agent and the workload-to-firewall inspect lines both turn amber, which the legend defines as collateral / alarm active, while the egress path from the firewall through the NAT gateway and the TLS :9142 and HTTPS · routing lines to the test endpoint turn red, which the legend defines as dropped (root cause).

Figure 13: Scenario 3 – The status page during a path-wide outage

Figure 13: Scenario 3 – The status page during a path-wide outage

Let DevOps Agent investigate. Both Alarm-2 and Alarm-3 fire in the same datapoint. DevOps Agent recognizes them as linked and merges them into a single investigation:

  1. Reads the flow logs and sees bidirectional TLS connections stop abruptly, with only one-way traffic remaining and no flows reaching the established state.
  2. Reads the firewall metrics and sees received and passed packets shift from one Availability Zone to the other at the moment of the change.
  3. Calls DescribeRouteTables and finds the egress route pointing at one Availability Zone firewall endpoint while the return route points at the other.
  4. Searches CloudTrail and surfaces the ReplaceRoute and CreateRoute calls by the same user, about a minute before both alarms fired.
  5. Reports the root cause as that asymmetric routing change. Recommends restoring symmetric same-Availability-Zone routing so egress and return traverse the same endpoint.
  6. Presents this as a plan you review and apply, not an automatic change.

A mitigation plan is a recommendation you review, not an automatic change, and the right fix depends on the intended design. Restoring symmetric routing can mean sending the workload subnet’s egress back through its own-Availability-Zone firewall endpoint (this sample’s architecture) or, in a design that doesn’t inspect this path, back through a NAT gateway. The agent infers a plausible target from what it can observe, so review the specific route it proposes against your intended topology before you apply it. (Connecting your pipeline or infrastructure-as-code, covered in the next section, lets the agent recommend the target that matches your design.)

In the DevOps Agent Operator Web App view, the agent restates the Alarm-3 (AsymmetricFlowFailures) trigger and confirms the workload’s egress to a monitored endpoint is being blocked by the Network Firewall (Figure 14).

Figure 14: Scenario 3 – The symptom

Figure 14: Scenario 3 – The symptom

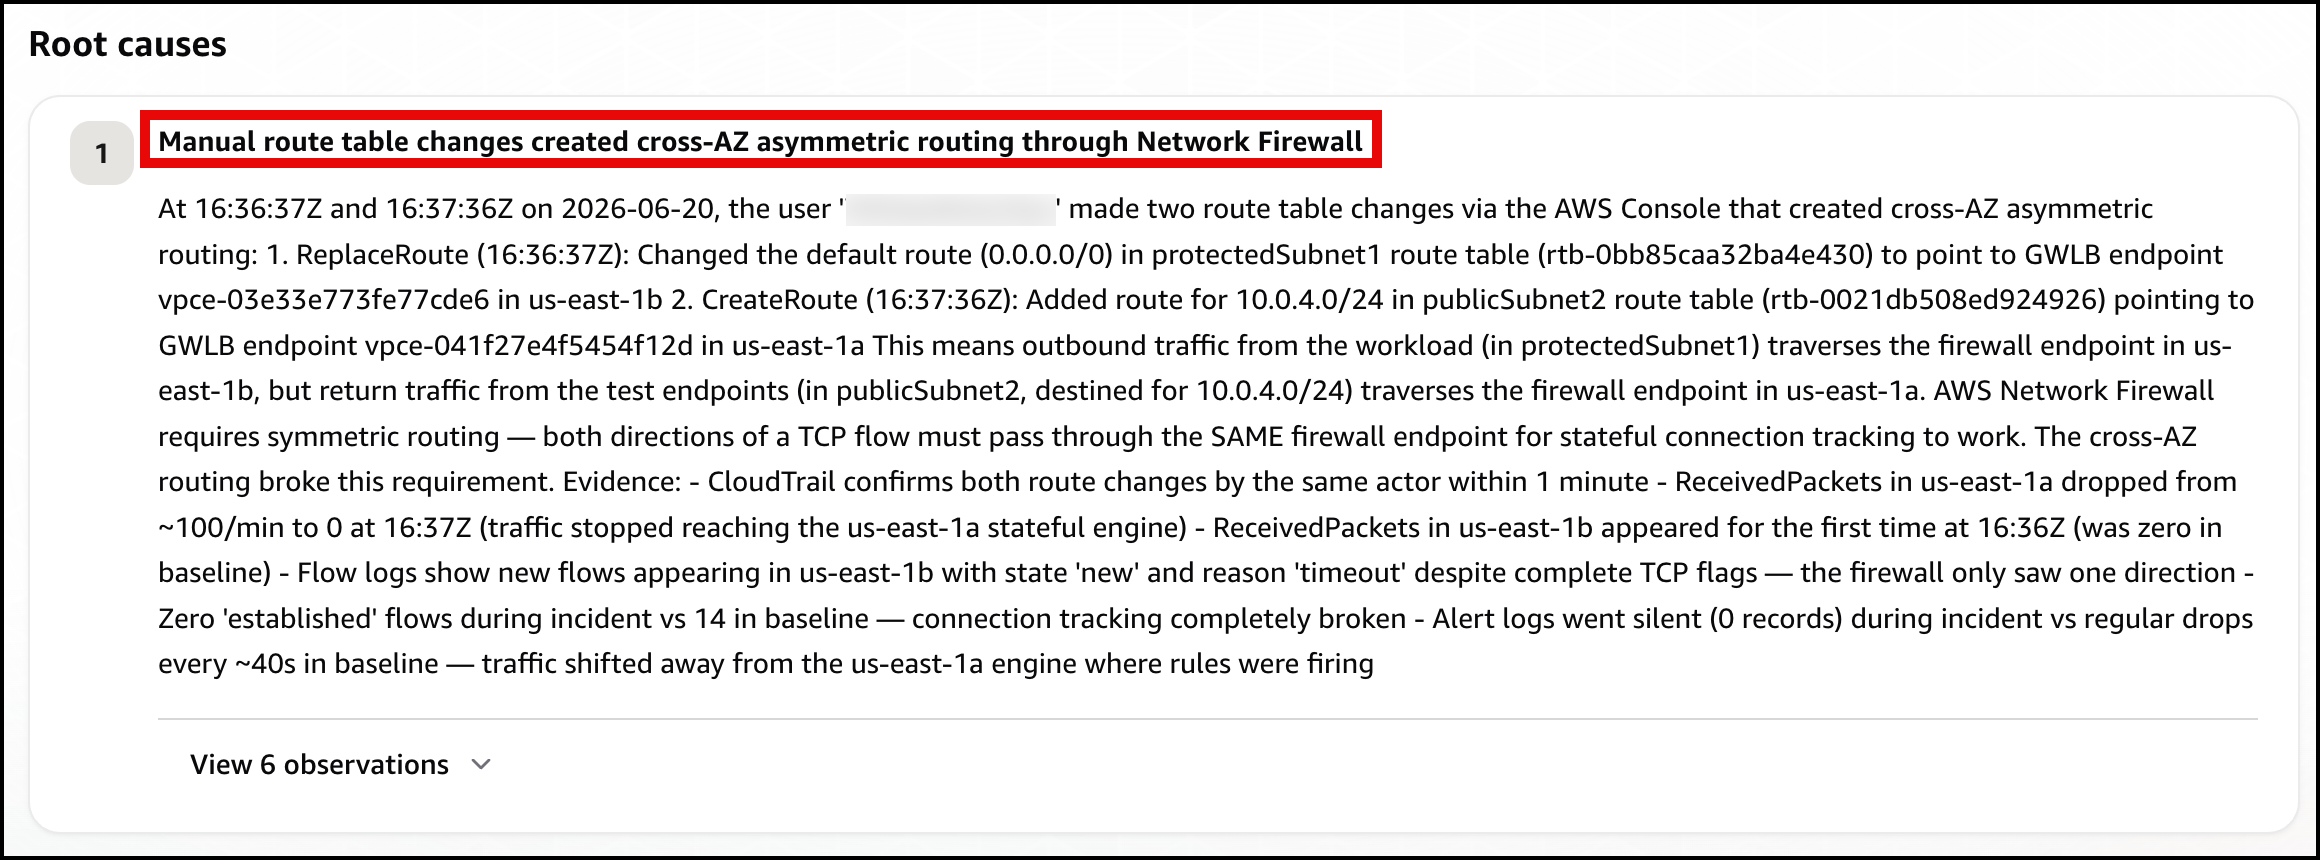
Next, the agent identifies the root cause: manual route table changes that created cross-AZ asymmetric routing through the network firewall, breaking its symmetric routing requirement (Figure 15)

Figure 15: Scenario 3 – The root cause

Figure 15: Scenario 3 – The root cause

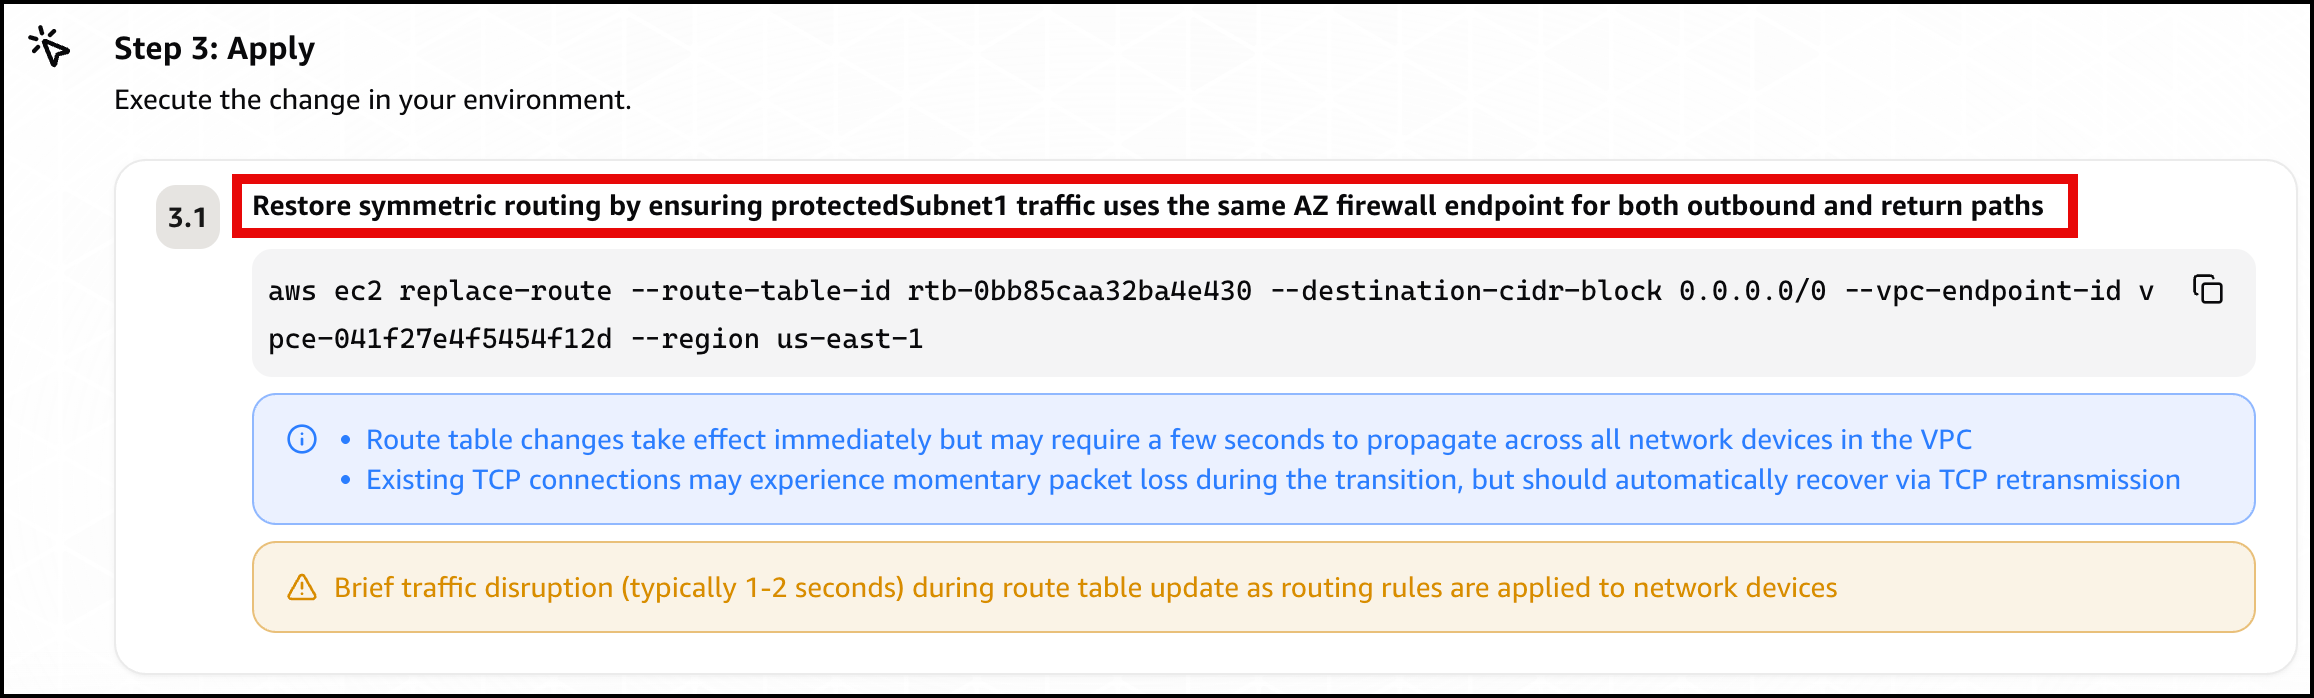
Finally, the agent presents a mitigation plan, recommending you restore symmetric routing by pointing protectedSubnet1‘s default route back to the same Availability Zone firewall endpoint, so one endpoint sees both directions of the flow again (Figure 16).

Figure 16: Scenario 3 – The mitigation plan

Figure 16: Scenario 3 – The mitigation plan

Confirm recovery. Apply the change the agent recommends, after checking the route target matches your intended design. After the workload subnet’s egress and return use the same Availability Zone firewall endpoint again, the control probe recovers, the alarms clear, and every card returns to green.

Further considerations

In production a single change can trigger several alarms at the same time, as Scenario 3 shows. DevOps Agent links related investigations and works them as one, so you review a single root cause. You can validate the linked findings or unlink an alarm to investigate it independently. If you would rather collapse alarms before they reach the agent, you can add correlation logic in the bridge Lambda function, buffering and grouping by firewall. You can also add email, Amazon Simple Queue Service (Amazon SQS), or HTTP subscribers to the SNS topic, or add the webhook Lambda function to a topic you already run. DevOps Agent produces a mitigation plan but does not change your environment on its own.

You can also give the agent more to work with. DevOps Agent connects to source repositories and CI/CD pipelines, integrating with GitHub (including GitHub Enterprise Server and GitLab Self-Managed through a private connection). It can associate AWS resources with deployments of AWS CloudFormation, AWS CDK, Amazon Elastic Container Registry (Amazon ECR) images, and Terraform. With deployed configuration and recent deployment events in view, the agent correlates the disruption against the change that introduced it and recommends a fix matching your intended design. For this sample, that means recommending the workload subnet’s own Availability Zone firewall endpoint rather than a generic symmetric path.

DevOps Agent also supports proactive incident prevention. It analyzes patterns across past investigations and delivers recommendations to prevent similar issues from recurring, including governance recommendations that strengthen deployment processes and pipeline controls. For Network Firewall rule changes, this means the agent can recommend guardrails for your CI/CD pipeline based on the classes of misconfigurations it has already resolved. You can access these recommendations through the Improvements page in the DevOps Agent Operator Web App.

Clean up

Clean up the environment with one command.

bash scripts/destroy.sh

It reverts any active scenario, runs cdk destroy for all stacks, and sweeps for stragglers by the Project = nf-devops-agent tag. The main cost drivers are the two Network Firewall endpoints, the NAT gateways (one in the main VPC for each Availability Zone, one in the test-endpoint VPC), and the test endpoint’s load balancers. Each of these bills at an hourly rate for as long as it’s provisioned, whether or not traffic is flowing, so a stack left running continues to accrue charges around the clock even while idle. Running the scenarios and tearing the stack down the same day limits the cost to a few active hours rather than days of idle hourly charges.

Conclusion

In this post, we showed you how AWS DevOps Agent accelerates troubleshooting for three common network firewall connectivity issues. The first was a domain deny list. The second was a stateless priority inversion. The third was an asymmetric cross-AZ routing drop. For each one, DevOps Agent investigated the drop and returned a root cause with a mitigation plan you approve before applying. The first scenario triggered on a prebuilt Network Firewall metric, and the other two on application health metrics. That shows both ways to alarm on a firewall problem through one pipeline.

The pattern isn’t specific to Network Firewall. The same flow fits any service that emits CloudWatch metrics and logs, such as AWS WAF, security groups, and network ACLs. Clone the sample repository to explore the solution, then apply what you learn to your own firewall, application, and alarms. For more details, see the AWS Network Firewall Developer Guide and the AWS Network Firewall pricing page. Start with the Getting Started with AWS DevOps Agent guide to connect your first webhook.

Salman Ahmed

Salman is a Senior Technical Account Manager at AWS, specializing in helping customers design, implement, and optimize their AWS environments. He combines deep networking expertise with a passion for exploring emerging technologies to help organizations get the most out of their cloud investments. Outside of work, he enjoys photography, traveling, and watching his favorite sports teams.

Keep your firewall rules up-to-date with Network Firewall features

Post Syndicated from Salman Ahmed original https://aws.amazon.com/blogs/security/keep-your-firewall-rules-up-to-date-with-network-firewall-features/

AWS Network Firewall is a managed firewall service that makes it simple to deploy essential network protections for your virtual private clouds (VPCs) on AWS. Network Firewall automatically scales with your traffic, and you can define firewall rules that provide fine-grained control over network traffic.

When you work with security products in a production environment, you need to maintain a consistent effort to keep the security rules synchronized as you make modifications to your environment. To stay aligned with your organization’s best practices, you should diligently review and update security rules, but this can increase your team’s operational overhead.

Since the launch of Network Firewall, we have added new capabilities that simplify your efforts by using managed rules and automated methods to help keep your firewall rules current. This approach can streamline operations for your team and help enhance security by reducing the risk of failures stemming from manual intervention or customer automation processes. You can apply regularly updated security rules with just a few clicks, enabling a wide range of comprehensive protection measures.

In this blog post, I discuss three features—managed rule groups, prefix lists, and tag-based resource groups—offering an in-depth look at how Network Firewall operates to assist you in keeping your rule sets current and effective.

Prerequisites

If this is your first time using Network Firewall, make sure to complete the following prerequisites. However, if you already created rule groups, a firewall policy, and a firewall, then you can skip this section.

Network Firewall and AWS managed rule groups

AWS managed rule groups are collections of predefined, ready-to-use rules that AWS maintains on your behalf. You can use them to address common security use cases and help protect your environment from various types of threats. This can help you stay current with the evolving threat landscape and security best practices.

AWS managed rule groups are available for no additional cost to customers who use Network Firewall. When you work with a stateful rule group—a rule group that uses Suricata-compatible intrusion prevention system (IPS) specifications—you can integrate managed rules that help provide protection from botnet, malware, and phishing attempts.

AWS offers two types of managed rule groups: domain and IP rule groups and threat signature rule groups. AWS regularly maintains and updates these rule groups, so you can use them to help protect against constantly evolving security threats.

When you use Network Firewall, one of the use cases is to protect your outbound traffic from compromised hosts, malware, and botnets. To help meet this requirement, you can use the domain and IP rule group. You can select domain and IP rules based on several factors, such as the following:

  • Domains that are generally legitimate but now are compromised and hosting malware
  • Domains that are known for hosting malware
  • Domains that are generally legitimate but now are compromised and hosting botnets
  • Domains that are known for hosting botnets

The threat signature rule group offers additional protection by supporting several categories of threat signatures to help protect against various types of malware and exploits, denial of service attempts, botnets, web attacks, credential phishing, scanning tools, and mail or messaging attacks.

To use Network Firewall managed rules

  1. Update the existing firewall policy that you created as part of the Prerequisites for this post or create a new firewall policy.
  2. Add a managed rule group to your policy and select from Domain and IP rule groups or Threat signature rule groups.

Figure 1 illustrates the use of AWS managed rules. It shows both the domain and IP rule group and the threat signature rule group, and it includes one specific rule or category from each as a demonstration.

Figure 1:  Network Firewall deployed with AWS managed rules

Figure 1: Network Firewall deployed with AWS managed rules

As shown in Figure 1, the process for using AWS managed rules has the following steps:

  1. The Network Firewall policy contains managed rules from the domain and IP rule groups and threat signature rule groups.
  2. If the traffic from a protected subnet passes the checks of the firewall policy as it goes to the Network Firewall endpoint, then it proceeds to the NAT gateway and the internet gateway (depicted with the dashed line in the figure).
  3. If traffic from a protected subnet fails the checks of the firewall policy, the traffic is dropped at the Network Firewall endpoint (depicted with the dotted line).

Inner workings of AWS managed rules

Let’s go deeper into the underlying mechanisms and processes that AWS uses for managed rules. After you configure your firewall with these managed rules, you gain the benefits of the up-to-date rules that AWS manages. AWS pulls updated rule content from the managed rules provider on a fixed cadence for domain-based rules and other managed rule groups.

The Network Firewall team operates a serverless processing pipeline powered by AWS Lambda. This processes the rules from the vendor source, first fetching them so that they can be manipulated and transformed into the managed rule groups. Then the rules are mapped to the appropriate category based on their metadata. The final rules are uploaded to Amazon Simple Storage Service (Amazon S3) to prepare for propagation in each AWS Region.

Finally, Network Firewall processes the rule group content Region by Region, updating the managed rule group object associated with your firewall with the new content from the vendor. For threat signature rule groups, subscribers receive an SNS notification, letting them know that the rules have been updated.

AWS handles the tasks associated with this process so you can deploy and secure your workloads while addressing evolving security threats.

Network Firewall and prefix lists

Network Firewall supports Amazon Virtual Private Cloud (Amazon VPC) prefix lists to simplify management of your firewall rules and policies across your VPCs. With this capability, you can define a prefix list one time and reference it in your rules later. For example, with prefix lists, you can group multiple CIDR blocks into a single object instead of managing them at an individual IP level by creating a prefix list for their specific use case.

AWS offers two types of prefix lists: AWS-managed prefix lists and customer-managed prefix lists. In this post, we focus on customer-managed prefix lists. With customer-managed prefix lists, you can define and maintain your own sets of IP address ranges to meet your specific needs. Although you operate these prefix lists and can add and remove IP addresses, AWS controls and maintains the integration of these prefix lists with Network Firewall.

To use a Network Firewall prefix list

  1. Create a prefix list.
  2. Update your existing rule group that you created as part of the Prerequisites for this post or create a new rule group.
  3. Use IP set references in Suricata compatible rule groups. In the IP set references section, select Edit, and in the Resource ID section, select the prefix list that you created.

Figure 2 illustrates Network Firewall deployed with a prefix list.

Figure 2: Network Firewall deployed with prefix list

Figure 2: Network Firewall deployed with prefix list

As shown in Figure 2, we use the same design as in our previous example:

  1. We use a prefix list that is referenced in our rule group.
  2. The traffic from the protected subnet goes through the Network Firewall endpoint and NAT gateway and then to the internet gateway. As it passes through the Network Firewall endpoint, the firewall policy that contains the rule group determines if the traffic is allowed or not according to the policy.

Inner workings of prefix lists

After you configure a rule group that references a prefix list, Network Firewall automatically keeps the associated rules up to date. Network Firewall creates an IP set object that corresponds to this prefix list. This IP set object is how Network Firewall internally tracks the state of the prefix list reference, and it contains both resolved IP addresses from the source and additional metadata that’s associated with the IP set, such as which rule groups reference it. AWS manages these references and uses them to track which firewalls need to be updated when the content of these IP sets change.

The Network Firewall orchestration engine is integrated with prefix lists, and it works in conjunction with Amazon VPC to keep the resolved IPs up to date. The orchestration engine automatically refreshes IPs associated with a prefix list, whether that prefix list is AWS-managed or customer-managed.

When you use a prefix list with Network Firewall, AWS handles a significant portion of the work on your behalf. This managed approach simplifies the process while providing the flexibility that you need to customize the allow or deny list of IP addresses according to your specific security requirements.

Network Firewall and tag-based resource groups

With Network Firewall, you can now use tag-based resource groups to simplify managing your firewall rules. A resource group is a collection of AWS resources that are in the same Region, and that match the criteria specified in the group’s query. A tag-based resource group bases its membership on a query that specifies a list of resource types and tags. Tags are key value pairs that help identify and sort your resources within your organization.

In your stateful firewall rules, you can reference a resource group that you have created for a specific set of Amazon Elastic Compute Cloud (Amazon EC2) instances or elastic network interfaces (ENIs). When these resources change, you don’t have to update your rule group every time. Instead, you can use a tagging policy for the resources that are in your tag-based resource group.

As your AWS environment changes, it’s important to make sure that new resources are using the same egress rules as the current resources. However, managing the changing EC2 instances due to workload changes creates an operational overhead. By using tag-based resource groups in your rules, you can eliminate the need to manually manage the changing resources in your AWS environment.

To use Network Firewall resource groups with a stateful rule group

  1. Create Network Firewall resource groups – Create a resource group for each of two applications. For the example in this blog post, enter the name rg-app-1 for application 1, and rg-app-2 for application 2.
  2. Update your existing rule group that you created as a part of the Prerequisites for this post or create a new rule group. In the IP set references section, select Edit; and in the Resource ID section, choose the resource groups that you created in the previous step (rg-app-1 and rg-app-2).

Now as your EC2 instance or ENIs scale, those resources stay in sync automatically.

Figure 3 illustrates resource groups with a stateful rule group.

Figure 3: Network Firewall deployed with resource groups

Figure 3: Network Firewall deployed with resource groups

As shown in Figure 3, we tagged the EC2 instances as app-1 or app-2. In your stateful rule group, restrict access to a website for app-2, but allow it for app-1:

  1. We use the resource group that is referenced in our rule group.
  2. The traffic from the protected subnet goes through the Network Firewall endpoint and the NAT gateway and then to the internet gateway. As it passes through the Network Firewall endpoint, the firewall policy that contains the rule group referencing the specific resource group determines how to handle the traffic. In the figure, the dashed line shows that the traffic is allowed while the dotted line shows it’s denied based on this rule.

Inner workings of resource groups

For tag-based resource groups, Network Firewall works with resource groups to automatically refresh the contents of the Network Firewall resource groups. Network Firewall first resolves the resources that are associated with the resource group, which are EC2 instances or ENIs that match the tag-based query specified. Then it resolves the IP addresses associated with these resources by calling the relevant Amazon EC2 API.

After the IP addresses are resolved, through either a prefix list or Network Firewall resource group, the IP set is ready for propagation. Network Firewall uploads the refreshed content of the IP set object to Amazon S3, and the data plane capacity (the hardware responsible for packet processing) fetches this new configuration. The stateful firewall engine accepts and applies these updates, which allows your rules to apply to the new IP set content.

By using tag-based resource groups within your workloads, you can delegate a substantial amount of your firewall management tasks to AWS, enhancing efficiency and reducing manual efforts on your part.

Considerations

Conclusion

In this blog post, you learned how to use Network Firewall managed rule groups, prefix lists, and tag-based resource groups to harness the automation and user-friendly capabilities of Network Firewall. You also learned more detail about how AWS operates these features on your behalf, to help you deploy a simple-to-use and secure solution. Enhance your current or new Network Firewall deployments by integrating these features today.

 
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
 

Salman Ahmed
Salman Ahmed

Salman is a Senior Technical Account Manager in AWS Enterprise Support. He enjoys helping customers in the travel and hospitality industry to design, implement, and support cloud infrastructure. With a passion for networking services and years of experience, he helps customers adopt various AWS networking services. Outside of work, Salman enjoys photography, traveling, and watching his favorite sports teams.

Network connectivity patterns for Amazon OpenSearch Serverless

Post Syndicated from Salman Ahmed original https://aws.amazon.com/blogs/big-data/network-connectivity-patterns-for-amazon-opensearch-serverless/

Amazon OpenSearch Serverless is an on-demand, auto-scaling configuration for Amazon OpenSearch Service. OpenSearch Serverless enables a broad set of use cases, such as real-time application monitoring, log analytics, and website search. OpenSearch Serverless lets you use OpenSearch without having to worry about scaling and managing an OpenSearch cluster. A collection can be accessed over the public internet or from your VPC. As you start accessing OpenSearch Serverless from different VPCs and accounts or from on premises, your connectivity patterns may change. In this post, we cover connectivity patterns and Domain Name System (DNS) resolution for your OpenSearch Serverless collection—whether accessed over the internet, within the VPC, within AWS, or from your on-premises location.

Foundational concepts

The following foundational concepts will help you better understand OpenSearch Serverless and DNS resolution.

Network access policy

The network access policy for OpenSearch Serverless determines whether the collection can be accessed over the internet or only through OpenSearch Serverless managed VPC endpoints. A single policy can be attached to multiple collections.

OpenSearch Serverless VPC endpoint

To access OpenSearch Serverless collections and dashboards privately from a VPC without using an internet gateway, you can create a VPC interface endpoint. When you create a VPC endpoint, it creates an elastic network interface (ENI) in each subnet that you enable for the VPC endpoint. These are requester-managed ENIs that serve as the entry point for traffic destined for the OpenSearch Serverless collection. When you create an OpenSearch Serverless VPC endpoint, the private DNS name option is enabled by default. This means that OpenSearch Serverless also creates an Amazon Route 53 private hosted zone and associates that with the VPC where the endpoint is created. This private hosted zone has a wildcard DNS record *.<region>.aoss.amazonaws.com pointing to the private DNS of the endpoint.

You create an OpenSearch Serverless VPC endpoint via the OpenSearch Serverless console or the OpenSearch Serverless API. You can’t create an OpenSearch Serverless VPC endpoint from the Amazon Virtual Private Cloud (Amazon VPC) console, although once created, you can see them on the VPC console as well.

Amazon Route 53 Resolver

Let’s understand what Amazon Route 53 Resolver does when an Amazon Elastic Compute Cloud (Amazon EC2) instance queries a DNS name. DNS queries originating from the VPC go to the Route 53 Resolver at the VPC+2 IP address. When a DNS query reaches the resolver, it checks if there are any Route 53 forward rules. If it matches, then it forwards the query to the DNS server provided by that rule. If the query remains unresolved, Route 53 Resolver proceeds to check the private hosted zones associated with the originating VPC. If it still remains unresolved, then it checks for VPC DNS, which helps to resolve EC2 DNS names. Lastly, if the query still isn’t resolved, Route 53 Resolver checks the public DNS. The following diagram illustrates this order or operations.

Route 53 DNS Overview

Route 53 Resolver inbound endpoints

Workloads utilizing resources both in a VPC and on premises need to resolve DNS records hosted on-premises and resources hosted in the VPC. With Route 53 Resolver inbound endpoints, you can resolve DNS queries to your VPC from your on-premises network or another VPC.

In the following sections, we provide an overview of connectivity patterns and DNS resolution.

Access an OpenSearch Serverless collection from Amazon EC2 (via internet gateway)

The following figure demonstrates the connectivity pattern to access an OpenSearch Serverless collection over the internet. The collection has an access type set to public, which allows authorized users to connect to the collection over the internet. An EC2 instance within the VPC can establish a connection to the collection via the internet gateway, and users outside the VPC can also access this collection over the internet.

Access an OpenSearch Serverless collection from Amazon EC2 (via internet gateway)

The workflow has the following steps, as indicated in the preceding diagram:

A. The EC2 instance performs a DNS lookup to Route 53 Resolver at a VPC+2 IP address. Route 53 Resolver returns the public IP addresses of the OpenSearch Serverless collection.

B. The EC2 instance sends a data request via an internet gateway to the OpenSearch Serverless collection using this public IP address.

C. An external client resolves to the public IP addresses of the OpenSearch Serverless collection and reaches it via the internet.

Now let’s perform a dig command for the collection or dashboard URL from the EC2 instance, and we observe that it’s resolving to a public IP address.

The following command uses an OpenSearch Serverless collection:

sh-5.2$ dig +short <collection-id>.<region>.aoss.amazonaws.com
192.0.2.10
198.51.100.204
192.0.2.45
198.51.100.55
192.0.2.100
203.0.113.66

The following command uses an OpenSearch dashboard:

sh-5.2$ dig +short dashboards.<region>.aoss.amazonaws.com
192.0.2.10
198.51.100.204
192.0.2.45
198.51.100.55
192.0.2.100
203.0.113.66

Now that you have implemented an OpenSearch Serverless collection with a network access policy as public, you can make the same collection accessible privately within the VPC. To achieve this, complete the following steps:

  1. Modify the network access policy of the collection and change the access type to VPC.
  2. Select the option Create VPC endpoints.

Access type for OpenSearch Serverless

  1. Choose the VPC and at least two subnets where you would like to have a VPC endpoint ENI for high availability.
  2. Choose Confirm to create the VPC endpoint.

Create VPC endpoints for Amazon OpenSearch Serverless

  1. Lastly, select the VPC endpoint and update the policy.

Access Type VPC Endpoint for Amazon OpenSearch Serverless

With the creation of the VPC endpoint, a Route 53 private hosted zone is also created within your account and associated with your VPC. In this setup, a CNAME record *.us-east-1.aoss.amazonaws.com is created to direct to the Regional AWS PrivateLink endpoint, as depicted in the following screenshot.

Route 53 Private Hosted Zone

Due to the private hosted zone associated with the VPC, Route 53 Resolver gives preference to the private hosted zone to resolve any DNS query originating from the VPC. DNS requests for the OpenSearch Serverless collection originating from the EC2 instance get resolved using this associated private hosted zone and resolve to the private IP addresses of the VPC endpoint, which allows Amazon EC2 to connect to the serverless collection via VPC endpoints vs. the internet gateway. We expand on this in the following section.

Access an OpenSearch Serverless collection from Amazon EC2 (via interface VPC endpoints)

The following figure demonstrates the connectivity pattern to access an OpenSearch Serverless collection privately from the VPC. The collection has an access type set to VPC endpoint, restricting access solely from the resources within the VPC via the VPC endpoint and preventing external users from connecting. With the creation of the VPC endpoint, a private hosted zone is also associated with this VPC. An EC2 instance within the VPC can establish a connection with the collection using the VPC endpoint, but resources outside of the VPC don’t have access to this collection because of the network access policy.

Access an OpenSearch Serverless collection from Amazon EC2 (via interface VPC endpoints)

The workflow consists of the following steps:

A. The EC2 instance performs a DNS lookup to Route 53 Resolver at a VPC+2 IP address. Route 53 Resolver returns the private IP addresses of the VPC endpoint because there is a private hosted zone associated with the VPC containing a CNAME record.

B. The EC2 instance sends a data request via the VPC interface endpoint to the OpenSearch Serverless collection.

C. An external client resolves to the public IP addresses of the OpenSearch Serverless collection but is unable to reach it because the network policy restricts to the VPC.

Now let’s perform a dig command for the collection or dashboard URL from the EC2 instance, and we observe that it’s resolving to the private IP addresses belonging to the VPC endpoints.

Use the following code for an OpenSearch Serverless collection:

sh-5.2$ dig +short <collection-id>.<region>.aoss.amazonaws.com
10.0.1.98
10.0.2.83

Use the following code for an OpenSearch dashboard:

sh-5.2$ dig +short dashboards.<region>.aoss.amazonaws.com
10.0.1.98
10.0.2.83

Access an OpenSearch Serverless collection from many VPCs (via interface VPC endpoints) with a VPC endpoint in each VPC

The following figure demonstrates the connectivity pattern to use the same VPC endpoint to connect to multiple OpenSearch Serverless collections. In this scenario, a VPC endpoint is created in each VPC to enable EC2 instances within the VPCs to utilize the VPC endpoint as the connectivity path to OpenSearch Serverless. A private hosted zone is auto generated for each endpoint and associated with the corresponding VPC. Network policies of OpenSearch Serverless collections are updated to allow both VPC Endpoint-1 and VPC Endpoint-2, which allows the EC2 instance in VPC-1 to access both collections via VPC Endpoint-1 and EC2 instances in VPC-2 to access both collections via VPC Endpoint-2.

Access an OpenSearch Serverless collection from many VPCs (via interface VPC endpoints) with a VPC endpoint in each VPC

The workflow consists of the following steps:

A. The EC2 instance performs a DNS lookup to Route 53 Resolver at a VPC+2 IP address. Route 53 Resolver returns the private IP addresses of the VPC endpoint (the EC2 instance in VPC-1 gets the IP address of VPC Endpoint-1 and the EC2 instance in VPC-2 gets the IP address of VPC Endpoint-2), because there is a private hosted zone associated with each of the VPCs containing a CNAME record.

B. The EC2 instance sends a data request via the VPC interface endpoint to the OpenSearch Serverless collection.

Access an OpenSearch Serverless collection from many VPCs (via interface VPC endpoints) with a VPC endpoint in a centralized VPC

In the previous connectivity pattern, we had one endpoint in each VPC through which VPC resources accessed OpenSearch Serverless collections. Many organizations would like to maintain control of these endpoints and keep these in a centralized VPC.

The following figure demonstrates the connectivity pattern to use a centralized VPC endpoint to connect to multiple OpenSearch Serverless collections from multiple VPCs. In this scenario, a VPC interface endpoint is created in a centralized VPC. A private hosted zone is auto generated for this VPC endpoint and associated with the centralized VPC, and then manually associated with VPC-1 and VPC-2. The DNS query for OpenSearch Serverless collections from VPC-1 and VPC-2 gets resolved to the centralized VPC endpoint due to the private hosted zone association. Network policies for both collections allow access from the centralized VPC endpoint only. All three VPCs (centralized, VPC-1, and VPC-2) are connected via AWS Transit Gateway and route tables have routes to direct traffic between VPC-1 and VPC-2 to the centralized VPC and vice versa.

Access an OpenSearch Serverless collection from many VPCs (via interface VPC endpoints) with a VPC endpoint in a centralized VPC

The workflow consists of the following steps:

A. The EC2 instance performs a DNS lookup to Route 53 Resolver at a VPC+2 IP address. Route 53 Resolver returns the private IP addresses of the centralized VPC endpoint, because there is a private hosted zone associated with each VPC containing a CNAME record.

B. The EC2 instance sends a data request to the Transit Gateway ENI in its own VPC. The Transit Gateway route table is checked and the data request is forwarded to the Transit Gateway ENI in the centralized VPC. The Transit Gateway ENI in the centralized VPC sends it to the OpenSearch Serverless collection via the VPC interface endpoint.

Access an OpenSearch Serverless collection from on premises (via AWS Site-to-Site VPN or AWS Direct Connect)

The following figure demonstrates the connectivity pattern for accessing OpenSearch Serverless collections from on premises. You can use either AWS Direct Connect or AWS Site-to-Site VPN to establish connectivity between on-premises and AWS resources. In the following example, Direct Connect is used for the connectivity between AWS and on premises. An OpenSearch Serverless VPC endpoint is created in the VPC, and a private hosted zone is automatically generated and associated with this VPC. The network policy of the OpenSearch Serverless collection is updated to allow connectivity only from the VPC endpoint.

To access these OpenSearch Serverless collections privately from the on-premises environment, resources need to resolve the OpenSearch Serverless collection DNS to the OpenSearch Serverless VPC endpoint IP address. By default, OpenSearch Serverless DNS resolves to the public IP addresses and attempts to access OpenSearch Serverless via the internet. To ensure that OpenSearch Serverless is accessed via the VPC endpoint from on premises, you need to ensure that DNS queries are resolved to a VPC endpoint’s private IP address. Resources inside the VPC use Route 53 Resolver, available at a VPC+2 IP address, to resolve these queries to the VPC endpoint. Route 53 Resolver checks the associated private hosted zone to resolve the query to the VPC endpoint. However, the VPC+2 IP address is not accessible from on premises. To address this, you can utilize the Route 53 Resolver inbound endpoint.

To achieve this, you can create an inbound endpoint in your VPC by following the steps outlined in Configuring inbound forwarding, and then update the on-premises DNS server to forward all the DNS requests for *.<region>.aoss.amazonaws.com to the IP address of the Route 53 Resolver inbound endpoint. When the on-premises client obtains the IP address of the VPC endpoint, it can use Direct Connect or Site-to-Site VPN to establish a private connection to the OpenSearch Serverless collection.

Access an OpenSearch Serverless collection from on premises (via AWS Site-to-Site VPN or AWS Direct Connect)

The workflow contains the following steps:

A. The on-premises client sends a DNS lookup to the on-premises DNS resolver. The on-premises DNS resolver forwards this request to the Route 53 Resolver inbound endpoint. The Route 53 Resolver inbound endpoint sends a DNS lookup to Route 53 Resolver at a VPC+2 IP address. Route 53 Resolver returns the private IP addresses of the VPC endpoint, because there is a private hosted zone associated with this VPC containing a CNAME record.

B. The on-premises client sends a data request to the OpenSearch Serverless collection, which routes via Direct Connect or Site-to-site VPN to the VPC interface endpoint and finally to the OpenSearch Serverless collection.

Conclusion

In this post, we showed you various connectivity patterns for OpenSearch Serverless. We covered the use of hybrid DNS and using a Route 53 Resolver inbound endpoint to allow connectivity from on premises for OpenSearch Serverless. You can choose from various centralization models for reaching multiple OpenSearch Serverless collections within the AWS Cloud or from on-premises locations. Get started today by connecting to OpenSearch Serverless from the various network patterns we discussed.


About the authors

Salman AhmedSalman Ahmed is a Sr. Technical Account Manager in AWS Enterprise Support. He enjoys working with Enterprise Support customers to help them with design, implementation and supporting cloud infrastructure. He also has a passion for networking services and with 12+ years of experience, he leverages that to help customers with adoption of AWS Transit Gateway, AWS Direct Connect and various other AWS networking services.

Ankush GoyalAnkush Goyal is Enterprise Support Lead in AWS Enterprise Support who helps enterprise support customers streamline their cloud operations on AWS. He is a results-driven IT professional with over 18 years of experience.

Rohit AswaniRohit Aswani is a Senior Specialist Solutions Architect focussed on Networking at AWS, where he helps customers build and design scalable, highly-available, secure, resilient and cost effective networks. He holds a MS in Telecommunication Systems Management from Northeastern University, specializing in Computer Networking. In his spare time, Rohit enjoys hiking, traveling and exploring new coffee places.