Post Syndicated from LastWeekTonight original https://www.youtube.com/shorts/hPYjLY3iQ9s
Python Workers are now generally available
Post Syndicated from Gyeongjae Choi original https://blog.cloudflare.com/python-workers-ga/
We introduced Python Workers two years ago, providing a way to run Python applications in the Cloudflare Workers runtime. Our goal was to make it as simple to write Workers in Python as it is in TypeScript, and to make the ecosystem of Python packages and frameworks “just work”.
Today, Python Workers are now generally available (GA).
What does GA mean? It means Python is now a first-class, fully supported language on the Cloudflare Developer Platform. You can bring the Python code, libraries, and design patterns you already know and connect them seamlessly to Workers AI, R2, D1, Hyperdrive, Durable Objects, Queues, Workflows, and the rest of the Cloudflare platform. You can also run popular Python frameworks like FastAPI, Django, and Flask inside Python Workers. You can even create a Python Worker inside another Worker using Dynamic Workers.
The journey behind Python Workers
Bringing Python to Cloudflare Workers was a natural choice. Because Workers has supported WebAssembly since 2018, it gave us the perfect environment to run a Wasm-compiled Python interpreter. By using Pyodide, we were able to quickly support a wide range of Python applications in Cloudflare Workers.
Our goal was to create the first platform for infinitely scalable Python apps, while making it as easy and performant as developing Python apps anywhere else.
The features we are highlighting today are the result of this multi-year effort. Many developers are already building applications within Python Workers; today, we are making these capabilities production-ready for everyone.
Python is now a first-class language in the Cloudflare Workers runtime
Python Workers now natively support Cloudflare Developer Platform bindings. Previously, using these Cloudflare bindings in Python Workers required converting Python objects into TypeScript objects explicitly at the RPC boundary. For example, sending a Python dictionary into a Cloudflare Queue required the following glue code to work:
This required Python developers to keep the JavaScript environment and code in mind while writing Python Workers, and it was a common source of error for both humans and AI agents. To address this, we have encapsulated the entire type conversion process within the Workers runtime and the Python SDK. This allows you to utilize all Cloudflare bindings in a Pythonic way without writing a single line of JavaScript code, making the following just work:
Web frameworks: FastAPI, Django, and Flask
You can now run your favorite Python framework, such as FastAPI, Django, or Flask, to build an API server in Python Workers. We implemented a built-in connector that you can use to easily connect your web application to Python Workers.
Let’s say you have a simple FastAPI web application:
In native environments, you would use a web server such as uvicorn to run this application.
In Python Workers, you can run the same application using the workers.asgi package we provide, just by adding this snippet to your code:
Similarly, you can use workers.wsgi package to run synchronous web applications such as Django.
So, what happens under the hood?
Python has a standard contract for how web applications should communicate with web servers, known as the Web Server Gateway Interface (WSGI), or its modern asynchronous counterpart, ASGI. This standard allows developers to build applications that are completely server-agnostic. In a traditional deployment, web servers like Uvicorn or Gunicorn are responsible for handling multiple concurrent client connections and threads to scale traffic, while web frameworks like FastAPI can focus purely on the application logic.
In Cloudflare Workers, the Workers platform itself serves as the web server. Since our global network already seamlessly handles load balancing and infinite scaling, we don't need to reinvent the wheel by running a server inside Python Workers.
Instead, our workers.asgi and workers.wsgi connectors act as a thin, optimized bridge. They translate the incoming native JavaScript request into the standard WSGI/ASGI structures that Python applications expect, and seamlessly pipe the response back out with minimal overhead. By doing this, Python developers get the best of both worlds: you can write and organize code using your favorite web frameworks, while letting the Cloudflare Workers platform instantly scale your API across the globe, without ever configuring a server.
These connectors can be used not only with FastAPI, Django, or Flask, but with any Python web framework that uses the WSGI or ASGI interface.
You can find more information about using each web framework in the Python Workers documentation.
Using PostgreSQL and MySQL with Hyperdrive
If you are building a Python application using relational databases such as PostgreSQL or MySQL, you can now integrate Hyperdrive into Python Workers.
Previously, Python Workers didn’t support TCP sockets, making database drivers unavailable. To understand why this was a blocker, you need to look at how WebAssembly operates. Python database drivers like aiomysql or asyncpg rely on the standard library's socket module to establish connections. In a standard environment, this module makes POSIX system calls to the underlying operating system. Inside a WebAssembly sandbox, those POSIX networking syscalls are normally stubs that always fail. Any attempt to open a standard socket would immediately fail. To solve this problem, we implemented socket system calls using the Workers connect API.
When a database driver attempts to open a TCP connection, it goes through our custom socket syscall implementation. It translates standard Python socket operations like opening a connection and reading bytes into the corresponding JavaScript calls used by the Workers runtime. Because this translation happens at the system call level, your database drivers don't have to know about the underlying implementation at all.
This socket bridge is what makes our Hyperdrive integration possible. To use Hyperdrive in Python Workers, first connect your database with Hyperdrive and set up the binding in the Wrangler config:
Then, connect to Hyperdrive using the database drivers you are familiar with:
You can refer to the Hyperdrive Python Workers documentation to find out how you can use Hyperdrive in Python Workers, and which packages are currently supported.
Expanding the WebAssembly package ecosystem
Because Python Workers run inside a WebAssembly sandbox, any packages with native C/C++/Rust extensions must be cross-compiled to WebAssembly to run in Python Workers. However, previously, there was no standard way to cross-compile any Python packages to WebAssembly. That meant our team had to manually compile and host custom WebAssembly packages. This greatly limited the number of packages you could actually use in Python Workers.
We wanted to fix this and allow users to use a wider variety of packages. However, we didn’t want to merely build packages usable only in Python Workers, which wouldn’t benefit the community. Since Python Workers are built on top of Pyodide, we wanted the ecosystem to evolve in a way that benefits Pyodide and the entire Python-on-WebAssembly community.
To this end, we proposed PEP 783, which standardizes a platform for running Python in the browser runtimes called PyEmscripten. After over a year of discussion and refinement, this proposal was accepted, enabling package maintainers to build and publish packages for the PyEmscripten platform and make them available across all environments that implement PyEmscripten.
We also stabilized the existing Pyodide build toolchain and evolved it into a form that is accessible to all package maintainers, enabling developers to easily build packages for the PyEmscripten platform. Furthermore, we added PyEmscripten platform support to cibuildwheel, to make it easier for others to adopt support for the PyEmscripten platform.
While the ecosystem is still adopting this standard, we hope every Python package will have a wheel that works with WebAssembly in the future. We are also actively working with major package maintainers to add PyEmscripten builds. If you encounter a package that isn’t supported yet, let us know on Discord or GitHub, and our team will work to get it built.
You can also check out our EuroPython 2026 talk: “Python Everywhere: The State of Python on WebAssembly” to see how we made this possible.
Building AI agents and pipelines in Python
The large ecosystem of data science and machine learning packages makes Python the natural choice for building intelligent agents and AI pipelines. But bringing these to Python Workers historically presented a challenge: libraries such as openai and langchain rely on HTTP clients like requests or httpx to communicate with external APIs. However, because of missing low-level socket operations support in Python Workers, these HTTP clients didn’t work properly.
To solve this, we contributed upstream to ensure these HTTP clients can route requests directly through the JavaScript fetch API in WebAssembly environments. Combined with our new support for low-level socket operations as explained in the previous section, this makes the entire networking stack work seamlessly inside Python Workers.
As a result, you can now run AI libraries like openai, langchain, and mcp natively in Python Workers. You can also combine them with Workers AI to run serverless inference on GPUs in Cloudflare’s network, or proxy requests through Cloudflare AI Gateway.
The example below shows a way to run Worker AI models in langchain, using the langchain-cloudflare package:
What you can build today
We have assembled a collection of production-ready patterns in our python-workers-examples repository. Here are some ways you can combine Python Workers with the Cloudflare ecosystem.
Asynchronous AI orchestration
Building a full-stack AI application often means connecting multiple services such as storage, queuing, and inference. This example shows how to build an AI-driven image-to-image generator purely in Python Workers. It accepts user requests, drops them into a Cloudflare Queue, and uses Workflows to orchestrate the image generation step via Workers AI, and stores the image to an R2 bucket.
Real-time stream processing with Bluesky Jetstream
Consuming a firehose of real-time events usually requires a dedicated server to maintain the connection. In this example, we use a Python Worker to connect to the ATProto/Bluesky Jetstream WebSocket. By backing this connection with a Durable Object, the Python Worker can maintain long-lived state, ensuring that the WebSocket connection stays alive.
More examples to explore
Model Context Protocol (MCP) Server
Build and deploy an MCP server using the official Python MCP package to give your AI assistants access to edge data.
Retrieval-Augmented Generation (RAG) system with Vectorize
Building a RAG system using Workers AI and Vectorize, Cloudflare’s vector database.
Python code examples across the Cloudflare developer docs
We’ve updated our docs across Cloudflare products to include Python example code. Nearly everywhere where there is a code example showing how to do something in TypeScript, there’s also a code example in Python. We’re committed to continuing to include Python examples across all of our products. You can toggle code snippets between JavaScript, TypeScript, and Python throughout our developer documentation.
What’s next?
Reaching GA is just the start. We have many plans to make Python Workers better, including making Python Workers more performant and memory efficient, as well as supporting more packages.
Keep telling us what you want to build on Python Workers, and we’ll keep pushing the bounds of what is possible. Check out Python Workers documentation and start building your first Python Worker!
Comic for 2026.09.21 – Work
Post Syndicated from Explosm.net original https://explosm.net/comics/work
New Cyanide and Happiness Comic
John Bulkeley and the Devil Boats
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=wZIJnn54BuA
UnitedHealthcare & UnitedHealth Group: Last Week Tonight with John Oliver (HBO)
Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=h1pXm0GjLho
S13 E23: UnitedHealthcare & UnitedHealth Group: 9/20/26: Last Week Tonight with John Oliver
Post Syndicated from LastWeekTonight original https://www.youtube.com/watch?v=Oz0y4CdYmvI
Prometheus and OpenTelemetry interoperability in 2026 – Survey results
Post Syndicated from original https://prometheus.io/blog/2026/09/21/otel-prometheus-interoperability-survey/
We ran a survey asking users of OpenTelemetry and Prometheus how they collect, process, and store metrics. The goal was to understand, with real usage data rather than assumptions, how far the ecosystem has moved and whether the interoperability still causes friction.
Key takeaways
- Interoperability has measurably improved since our 2024 survey: the average ease-of-use rating rose from 3.1 to 3.6, the equivalent of one in two respondents rating a whole category higher, and the share of respondents finding the two hard to use together fell from 29% to 10%.
- In infrastructure instrumentation, Prometheus exporters remain the most-used method (72%) with OTel receivers close behind (57%), and nearly half of respondents run both at once rather than migrating from one to the other.
- In application instrumentation, OTel SDKs are the most-used method at 65% with Prometheus SDKs at 52%, and 41% use only the OTel style of application instrumentation.
- Prometheus relabeling rules (54%) and the open source OTel Collector (53%) are the two most common processing steps, and 65% of respondents run a “vanilla stack” of one or both with no vendor transformation or custom Collector build anywhere in the pipeline.
Demographics
From 186 people who responded, 81 passed our screening for active OpenTelemetry-for-metrics users on a Prometheus-adjacent backend. We also filtered out observability vendor employees to focus on end users. In the analyzed sample:
- All respondents are active OpenTelemetry users.
- All respondents use some flavor of Prometheus – Prometheus itself (46%), an open source Prometheus-compatible backend such as Thanos, Cortex, or Grafana Mimir (42%), or a PromQL-compatible vendor product (12%).
- Respondents’ observability maturity is high. 48% describe their organization as having “a well-established observability practice” (Expert), 41% are “setting up an observability practice” (Intermediate), while only 11% consider themselves beginners in observability.
- Organizations skew large. 42% have 1,000+ employees, 31% have 100–999, 15% have 50–99, and 12% report having under 50.
Ease of use change over time
How easy or difficult is it to use OpenTelemetry and Prometheus together?
This year, we asked the same question as in the similar 2024 survey to see whether end users saw progress in interoperability.
The average rating rose by 0.5 point, from 3.1 to 3.6 — as if every second respondent had moved up a full category. The clearest movement is at the difficult end of the scale: the share of respondents who found the two hard to use together dropped to roughly a third of its 2024 level. Also, nobody this year picked “Very difficult”.
Two years of work on interoperability is paying off. At the same time, since the single largest group of responses sits at “Neither easy nor difficult”, there is still a lot of work to be done in this area.
Note: The 2024 survey didn’t ask respondents whether they worked for an observability vendor, so this is not an exact apples-to-apples population match. However, putting vendor employees back into the 2026 sample (n = 108) would barely change the result for the ease of use rating (0%, 10%, 40%, 33%, 17% → 0%, 10%, 41%, 33%, 16%). To keep this year’s results consistent, we decided to stick with filtering vendor employees out.
Infrastructure metrics
How do you instrument infrastructure metrics collection?
Prometheus exporters are the most common single instrumentation method for infrastructure metrics but OTel receivers are close behind. Built-in /metrics endpoint, built-in OTLP push, and OpenTelemetry eBPF instrumentation (OBI) follow.
When looking at how these methods combine, the picture is clearly hybrid, not either/or. Nearly half of respondents are mixing Prometheus and OTel instrumentation styles at once for infrastructure metrics, rather than doing a full migration. Among respondents using a single instrumentation style, Prometheus-only style is twice as popular as OTel-only style.
Note: Instrumentation style describes whether a respondent uses methods native to one project only, or a mix of both. OTel-style includes using OTel receivers, Built-in OTLP push, or OpenTelemetry eBPF Instrumentation (OBI). Prometheus-style includes Prometheus exporters or Built-in /metrics endpoint (no exporter). The 4 “Other” responses are write-ins: Zabbix, Heorku Telemetry (likely “Heroku Telemetry”), textfile collector, Telegraf. All 4 respondents also selected a real Prometheus/OTel method alongside their write-in — but in the style chart above, a write-in places a respondent in “Other” regardless of what else they selected.
Work in progress: The Prometheus and OTel communities are working on making Prometheus exporters run as an OTel Collector distribution. The conversations are still ongoing. The discussion is open in this issue.
Application metrics
How do you instrument application metrics collection?
Preferences swap for application instrumentation. OTel SDKs come out on top with Prometheus SDKs following behind them. OBI holds roughly the same share as in infrastructure instrumentation.
Instrumentation styles shift as well. The largest share of participants (41%) use only OTel style instrumentation, nearly twice as common as only Prometheus style. Fewer than a third mix styles.
Note: In application instrumentation, OTel-style includes using OTel SDKs or OpenTelemetry eBPF Instrumentation (OBI). Prometheus-style includes Prometheus SDKs. Again, there are 4 write-ins that we categorized as “Other”: already built exporters, Micrometer, textfile collector, jvm-exporter. 3 of the 4 also selected a real Prometheus/OTel method. One respondent’s original write-ins, “Self instrumentation” and “manual instrumentation for OTEl,” were recoded to plain OTel SDKs.
Transformation
What do you use to process or transform metrics before sending them to storage?
Prometheus relabeling rules and the open source OTel Collector are the two most common processing steps with neither of them leading clearly.
Most respondents run a vanilla stack: only Prometheus relabeling rules and/or the plain OTel Collector, with no vendor distribution and no custom-built Collector in the pipeline. The three vanilla patterns come out close to even.
Note: “Other” combines respondents who do no transformation at all (15%, n=12) with those using a vendor distribution or custom-built Collector (20%, n=16).
What practitioners want improved
What would you like us to improve to make OpenTelemetry and Prometheus work better together?
We received 19 open-ended responses with suggestions on what to improve. Three themes emerged from this data: unification of Prometheus and OTel’s data models (attributes/labels), better handling of resource attributes and metadata, and naming and formatting friction. There were also a few individual asks. Prometheus maintainers György “Krajo” Krajcsovits and Arthur Sens went through the responses and addressed each point below:
- Unifying Prometheus and OTel’s data models (attributes/labels)
- This is a valid ask that we recognize. We will raise it for a discussion at the Prometheus Dev summit in October.
- Resource attributes and metadata gaps
- This should be addressed by the native metadata design doc. One thing that we have to wait for is finishing the OTel Entities spec.
- Naming and formatting friction
- Several relevant things already exist — the OpenMetrics 2.0 exposition format lets OTel-style names be used directly in code, PromQL already supports UTF-8 metric names, and Prometheus’s OTLP receiver has configurable translation strategies. The pieces exist; they’re just not the default yet. We have to work on this.
- Using Prometheus native recording rules in the Collector
- There’s an open Prometheus proposal and proof-of-concept PR for scrape-time recording rules, which wouldn’t need a full TSDB the way recording rules do today. Since the OpenTelemetry Collector’s Prometheus Receiver uses Prometheus code as a Go Library, this proposal would also benefit the Collector.
- Enable MCP or agentic AI workflows
- Prometheus just onboarded the Prometheus MCP project repository to its GitHub org. This should enable MCP workflows for Prometheus. The Prometheus community would love to see people start using it and get feedback. Also, the native metadata design doc explains how we plan to make agentic AI workflows even better in Prometheus.
Interesting observations
Mid-size organizations may be furthest into OTel-native tooling
In our data, organizations with 100-999 employees have the highest OTel SDK adoption for application metrics and OTel receiver adoption for infrastructure metrics. eBPF-based instrumentation (OBI) doesn’t follow the same pattern — there, it’s the 1,000+ organizations that stand apart from every smaller band.
Adoption by organization size:
| Organization size | OTel SDKs(application) | OTel receivers(infrastructure) | eBPF / OBI(infrastructure) |
|---|---|---|---|
| 1–49 (n = 10) | 40% | 20% | 20% |
| 50–99 (n = 12) | 58% | 58% | 17% |
| 100–999 (n = 25) | 84% | 76% | 20% |
| 1,000+ (n = 34) | 62% | 53% | 3% |
Our hypothesis is that mid-size organizations — big enough to have a dedicated platform effort, small enough to move without a multi-year migration plan — might be pushing furthest into newer OTel-native tooling.
Note: This is an interesting observation and a hypothesis, not a confirmed finding: with 10–34 respondents per band, none of these gaps is big enough for a survey this size to confirm.
Team type tracks backend choice
Platform Engineering and SRE teams lean heavily toward OSS Prometheus-compatible backends (Thanos, Cortex, Mimir), while Dev teams lean the other way, toward plain Prometheus.
Here, the dividing line looks like operational ownership rather than preference. Teams running metrics for a whole organization eventually outgrow a single Prometheus deployment, whereas teams instrumenting their own service generally don’t.
Backend choice by team type — OSS Prometheus-compatible (n = 30), Prometheus (n = 35), PromQL-compatible vendor (n = 8):
| Team type | OSS Prometheus-compatible | Prometheus | PromQL-compatible vendor |
|---|---|---|---|
| Dev | 24% | 71% | 6% |
| DevOps | 23% | 62% | 15% |
| Observability | 29% | 41% | 29% |
| Platform Engineering | 69% | 31% | 0% |
| SRE | 69% | 31% | 0% |
Note: Sysadmin (n = 6) and Operations (n = 2) respondents are excluded from this table — both groups are too small to interpret — leaving n = 73 of the 81 respondents. As with the previous breakdown, the per-band numbers here (8 to 35) are too small to draw firm conclusions.
Get involved
Interoperability is measurably easier than it was two years ago, but the open-ended answers point to concrete gaps — data model differences, resource attributes and metadata gaps, and naming and formatting friction. There is still a lot of work to do on both the OpenTelemetry and the Prometheus side.
Everyone is welcome to contribute. The discussion happens in the #otel-prometheus channel in the CNCF Slack.
NOTE: This blog post was also published on opentelemetry.io/blog (canonical version).
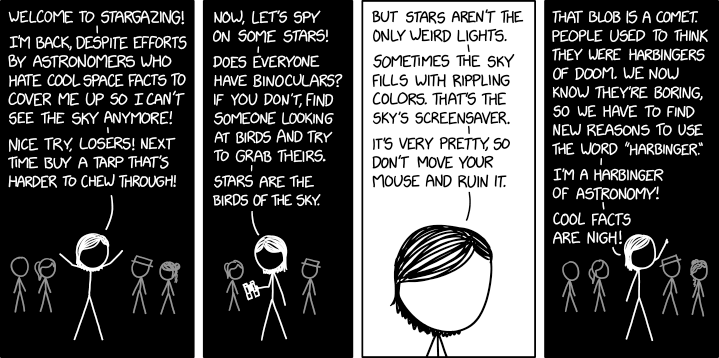
Stargazing 5
Post Syndicated from xkcd.com original https://xkcd.com/3301/
Kernel prepatch 7.3-rc4
Post Syndicated from jake original https://lwn.net/Articles/1095491/
Linus Torvalds has released the 7.3-rc4
kernel prepatch. It is, unsurprisingly at this point, large: “We all know the drill by now: ‘it’s big, yadda yadda’
“.
NVIDIA MMS1X00-N5400 QSFP112 1310NM 400Gbps Optic Quick Look
Post Syndicated from Rohit Kumar original https://www.servethehome.com/nvidia-mms1x00-n5400-qsfp112-1310nm-400gbps-optic-quick-look/
We take a look at the NVIDIA MMS1X00-N5400 which are 500m QSFP112 modules desgined to link devices at up to 500m distances
The post NVIDIA MMS1X00-N5400 QSFP112 1310NM 400Gbps Optic Quick Look appeared first on ServeTheHome.
Malcolm Gladwell Jokes About Who’d Win a Hypothetical U.S.-Canada War
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/PpLm_JgGEm4
Does the Enormousness of the Universe Make Us Insignificant?
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/2ZorQqTRRIo
Former White House Adviser Karl Rove on Members of GOP Who Traffic in Bigotry, Conspiracies
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/RAaz1sBx6Y0
Comic for 2026.09.20 – 2 months
Post Syndicated from Explosm.net original https://explosm.net/comics/2-months
New Cyanide and Happiness Comic
PBS’s Amna Nawaz on Trump’s treatment of women in the press corps
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/k-BoS4xX8kQ
David Brooks Discusses Black Holes, Dark Matter, and the Multiverse With Priyamvada Natarajan
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=4sIuJEFZv7g
Former White House Chief of Staff Andrew Card on remembering 9/11
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/SSNI_5MuYOs
Colin Kaepernick says NFL players feared retaliation for protesting
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/oApoE7LunrE
Good Ideas
Post Syndicated from Oglaf! -- Comics. Often dirty. original https://www.oglaf.com/goodideas/
Rahm Emanuel on Where He Thinks Democrats Should Focus for the Midterms
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/UqU7jS_JD-4