Pull requests are the beating heart of GitHub. As engineers, this is where we spend a good portion of our time. And at GitHub’s scale—where pull requests can range from tiny one-line fixes to changes spanning thousands of files and millions of lines—the pull request review experience has to stay fast and responsive.
We recently shipped the new React-based experience for the Files changed tab (now the default experience for all users). One of our main goals was to ensure a more performant experience across the board, especially for large pull requests. That meant investing in, and consistently prioritizing, the hard problems like optimized rendering, interaction latency, and memory consumption.
For most users before optimization, the experience was fast and responsive. But when viewing large pull requests, performance would noticeably decline. For example, we observed that in extreme cases, the JavaScript heap could exceed 1 GB, DOM node counts surpassed 400,000, and page interactions became extremely sluggish or even unusable. Interaction to Next Paint (INP) scores (a key metric in determining responsiveness) were above acceptable levels, resulting in an experience where users could quantifiably feel the input lag.
Our recent improvements to the Files changed tab have meaningfully improved some of these core performance metrics. While we covered several of these changes briefly in a recent changelog, we’re going to cover them in more detail here. Read on for why they mattered, what we measured, and how those updates improved responsiveness and memory pressure across the board and especially in large pull requests.
Performance improvements by pull request size and complexity
As we started to investigate and plan our next steps for improving these performance issues, it became clear early on that there wouldn’t be one silver bullet. Techniques that preserve every feature and browser-native behavior can still hit a ceiling at the extreme end. Meanwhile, mitigations designed to keep the worst-case from tipping over can be the wrong tradeoff for everyday reviews.
Instead of looking for a single solution, we began developing a set of strategies. We selected multiple targeted approaches, each designed to address a specific pull request size and complexity.
Those strategies focused on the following themes:
Focused optimizations for diff-line components. Make the primary diff experience efficient for most pull requests. Medium and large reviews stay fast without sacrificing expected behavior, like native find-in-page.
Gracefully degrade with virtualization. Keep the experience usable for the largest pull requests. Prioritize responsiveness and stability by limiting what is rendered at any moment.
Invest in foundational components and rendering improvements. These compound across every pull request size, regardless of which mode a user ends up in.
With these strategies in mind, let’s explore the specific steps we took to address these challenges and how our initial iterations set the stage for the improvements that followed.
First steps: Optimizing diff lines
With our team’s goal of improving pull request performance, we had three main objectives:
Reduce memory and JavaScript heap size.
Reduce the DOM node count.
Reduce our average INP and significantly improve our p95 and p99 measurements
To hit these goals, we focused on simplification: less state, fewer elements, less JavaScript, and fewer React components. Before we look at the results and new architecture, let’s take a step back and look at where we started.
What worked and what didn’t with v1
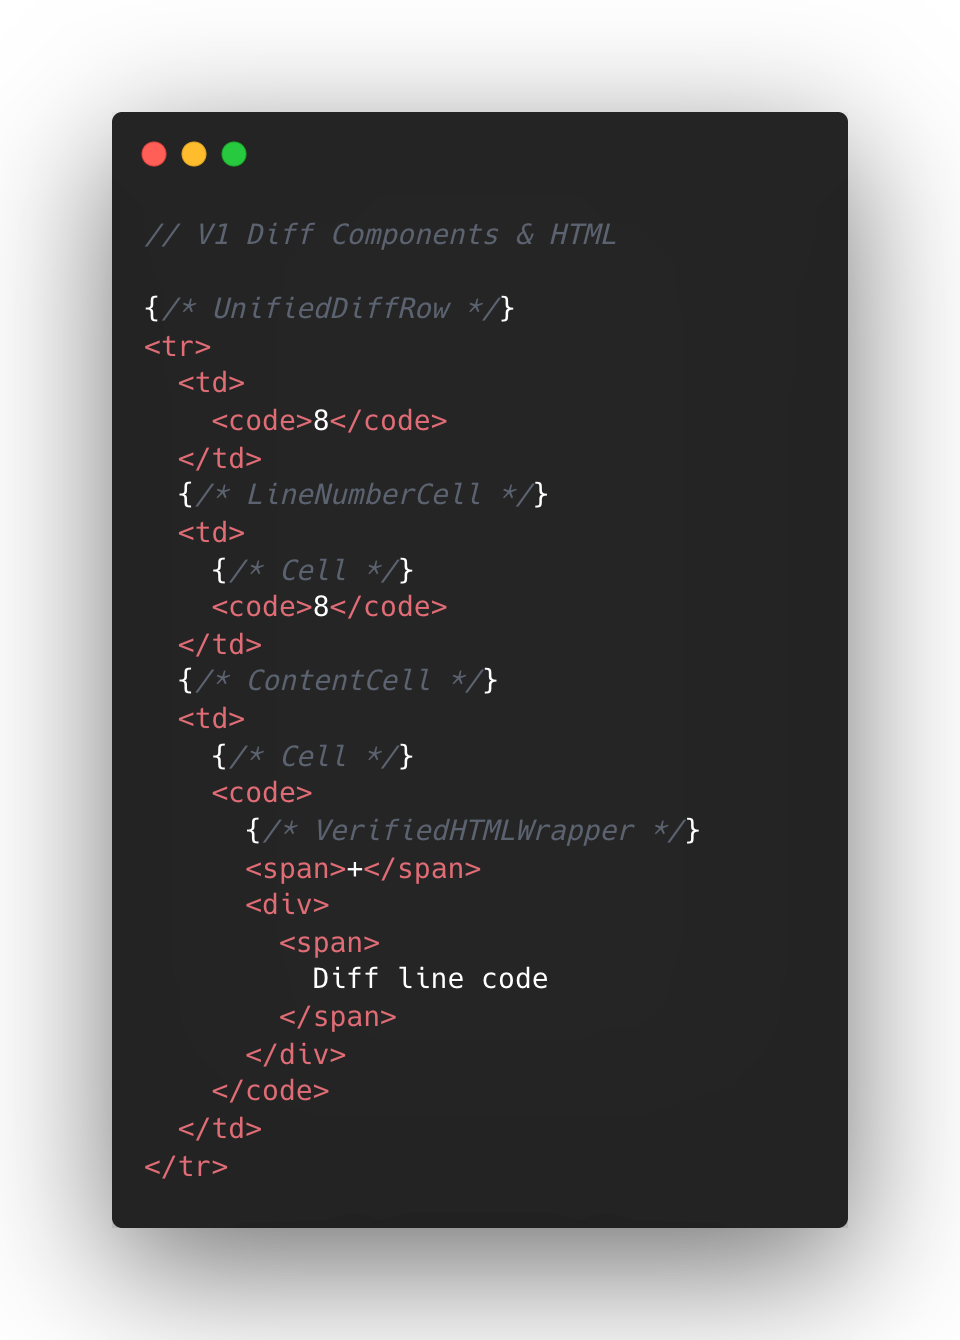
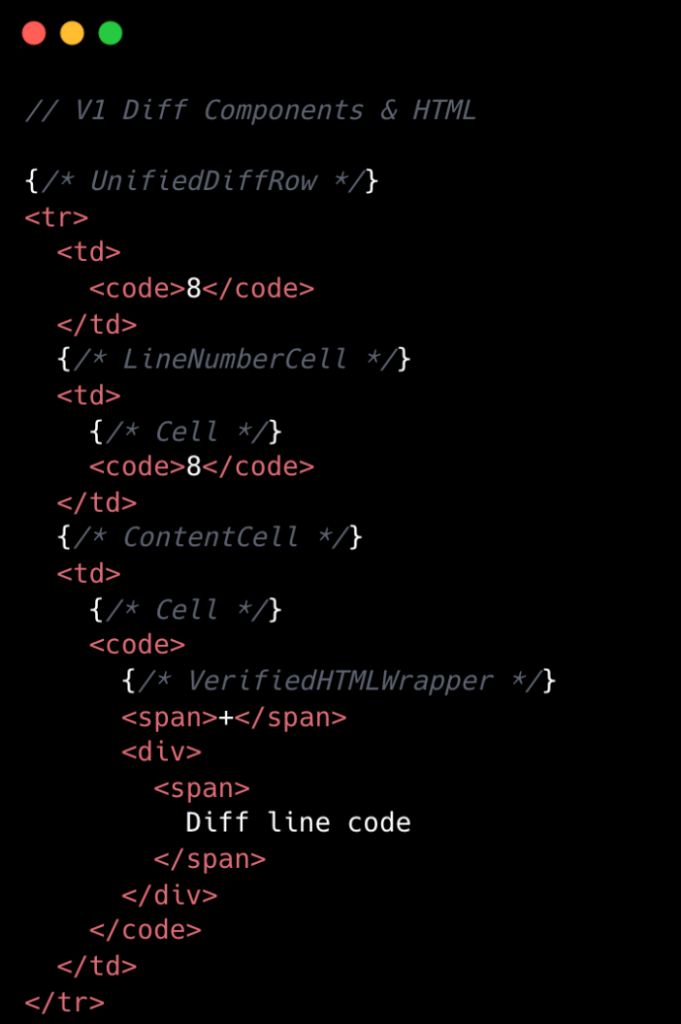
In v1, each diff line was expensive to render. In unified view, a single line required roughly 10 DOM elements; in split view, closer to 15. That’s before syntax highlighting, which adds many more <span> tags and drives the DOM count even higher.
The following is a simplified visual of the React Component structure mixed with the DOM tree elements for v1 diffs.
At the React layer, unified diffs typically contain at least eight components per line, while the split view contain a minimum of 13. And these numbers represent baseline counts; extra UI states like comments, hover, and focus could add more components on top.
This approach made sense to us in v1, when we first ported the diff lines to React from our classic Rails view. Our original plan centered around lots of small reusable React components and maintaining DOM tree structure.
But we also ended up attaching a lot of React event handlers in our small components, often five to six per component. On a small scale, that was fine, but on a large scale that compounded quickly. A single diff line could carry 20+ event handlers multiplied across thousands of lines.
Beyond performance impact, it also increased complexity for developers. This is a familiar scenario where you implement an initial design, only to discover later its limitations when faced with the demands of unbounded data.
To summarize, for every v1 diff line there would be:
Minimum of 10-15 DOM tree elements
Minimum of 8-13 React Components
Minimum of 20 React Event Handlers
Lots of small re-usable React Components
This v1 strategy proved unsustainable for our largest pull requests, as we consistently observed that larger pull request sizes directly led to slower INP and increased JavaScript heap usage. We needed to determine the best path for improving this setup.
Small changes make a large impact: v2
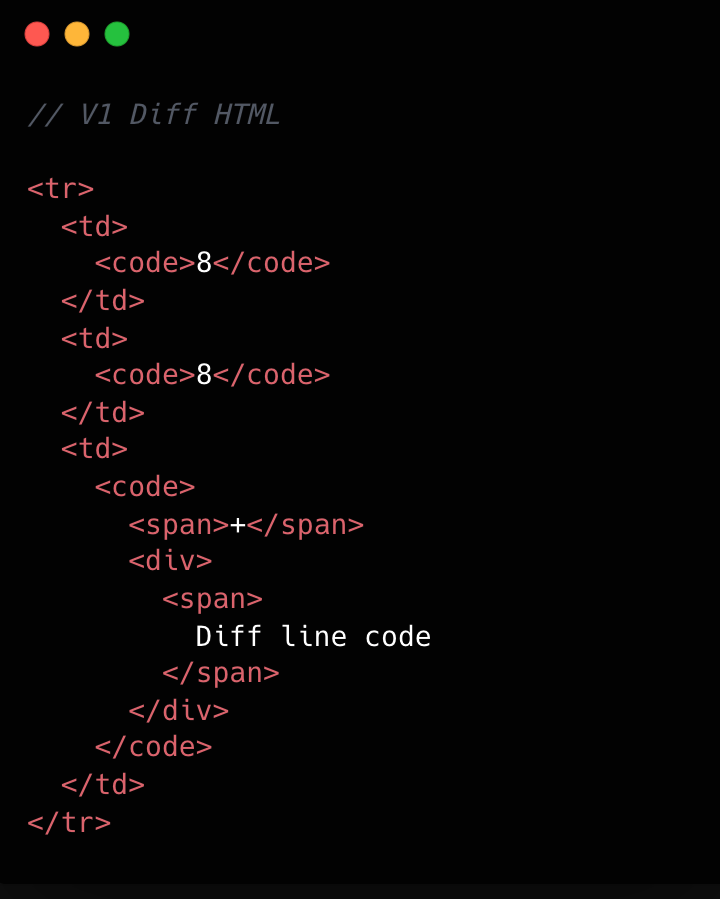
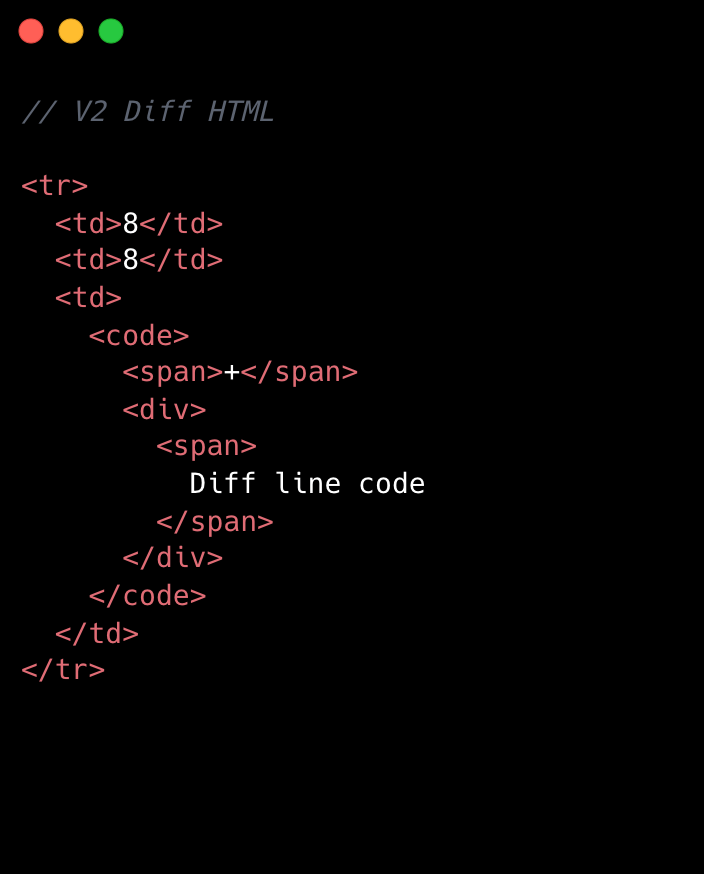
No change is too small when it comes to performance, especially at scale. For example, we removed unnecessary <code> tags from our line number cells. While dropping two DOM nodes per diff line might appear minor, across 10,000 lines, that’s 20,000 fewer nodes in the DOM. These kinds of targeted, incremental optimizations, no matter how small, compound to create a much faster and more efficient experience. By not overlooking these details, we ensured that every opportunity for improvement was captured, amplifying the overall impact on our largest pull requests.
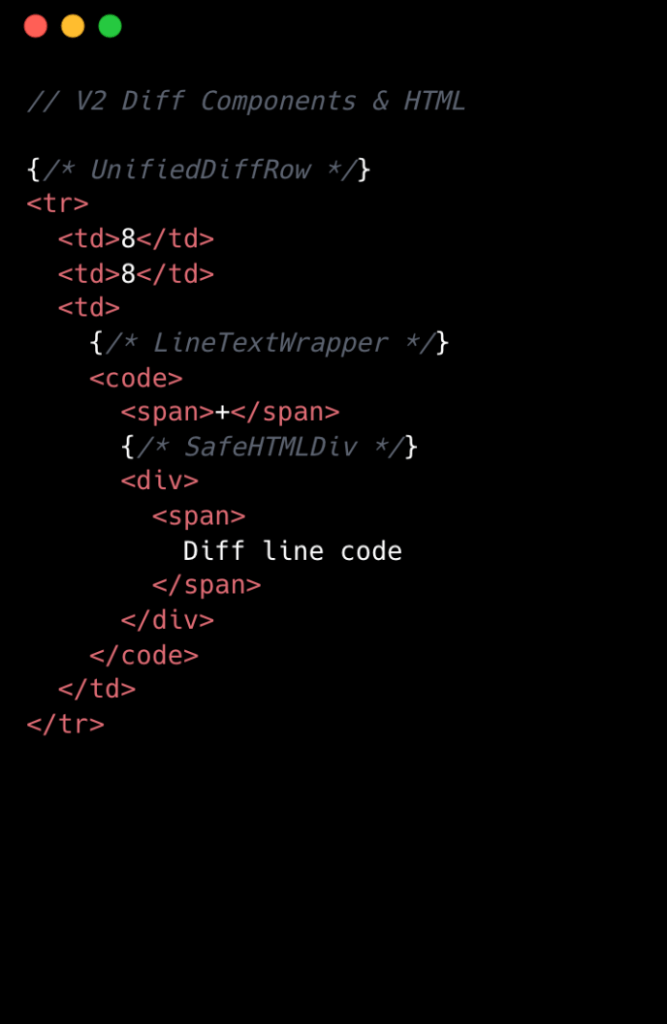
Refer to the images below to see how v1 looks compared to v2.
This becomes clearer if we look at the component structure behind this HTML:
We went from eight components per diff line to two. Most of the v1 components were thin wrappers that let us share code between Split and Unified views. But that abstraction had a cost: each wrapper carried logic for both views, even though only one rendered at a time. In v2, we gave each view its own dedicated component. Some code is duplicated, but the result is simpler and faster.
Simplifying the component tree
For v2, we removed deeply nested component trees, opting for dedicated components for each split and unified diff line. While this led to some code duplication, it simplified data access and reduced complexity.
Event handling is now managed by a single top-level handler using data-attribute values. So, for instance, when you click and drag to select multiple diff lines, the handler checks each event’s data-attribute to determine which lines to highlight, instead of each line having its own mouse enter function. This approach streamlines both code and improves performance.
Moving complex state to conditionally rendered child components
The most impactful change from v1 to v2 was moving app state for commenting and context menus into their respective components. Given GitHub’s scale, where some pull requests exceed thousands of lines of code, it isn’t practical for every line to carry complex commenting state when only a small subset of lines will ever have comments or menus open. By moving the commenting state into the nested components for each diff line, we ensured that the diff-line component’s main responsibility is just rendering code—aligning more closely with the Single Responsibility Principle.
O(1) data access and less “useEffect” hooks
In v1, we gradually accumulated a lot of O(n) lookups across shared data stores and component state. We also introduced extra re-rendering through useEffect hooks scattered throughout the diff-line component tree.
To address this in v2, we adopted a two-part strategy. First, we restricted useEffect usage strictly to the top level of diff files. We also established linting rules to prevent the introduction of useEffect hooks in line-wrapping React components. This approach enables accurate memoization of diff line components and ensures reliable, predictable behavior.
Next, we redesigned our global and diff state machines to utilize O(1) constant time lookups by employing JavaScript Map. This let us build fast, consistent selectors for common operations throughout our codebase, such as line selection and comment management. These changes have enhanced code quality, improved performance, and reduced complexity by maintaining flattened, mapped data structures.
Now, any given diff line simply checks a map by passing the file path and the line number to determine whether or not there are comments on that line. An access might look like: commentsMap[‘path/to/file.tsx’][‘L8’]
Did it work?
Definitely. The page runs faster than it ever did, and JavaScript heap and INP numbers are massively reduced. For a numeric look, check out the results below. These metrics were evaluated on a pull request using a split diff setting with 10,000 line changes in the diff comparison.
Metric
v1
v2
Improvement
Total lines of code
2,800
2,000
27% less
Total unique component types
19
10
47% fewer
Total components rendered
~183,504
~50,004
74% fewer
Total DOM nodes
~200,000
~180,000
10% fewer
Total memory usage
~150-250 MB
~80-120 MB
~50% less
INP on a large pull request using m1 MacBook pro with 4x slowdown:
~450 ms
~100 ms
~78% faster
As you can see, this effort had a massive impact, but the improvements didn’t end there.
Virtualization for our largest pull requests
When you’re working with massive pull requests—p95+ (those with over 10,000 diff lines and surrounding context lines)—the usual performance tricks just don’t cut it. Even the most efficient components will struggle if we try to render tens of thousands of them at once. That’s where window virtualization steps in.
In front-end development, window virtualization is a technique that keeps only the visible portion of a large list or dataset in the DOM at any given time. Instead of loading everything (which would crush memory and slow things to a crawl), it dynamically renders just what you see on screen, and swaps in new elements as you scroll. This approach is like having a moving “window” over your data, so your browser isn’t bogged down by off-screen content.
To make this happen, we integrated TanStack Virtual into our diff view, ensuring that only the visible portion of the diff list is present in the DOM at any time. The impact was huge: we saw a 10X reduction in JavaScript heap usage and DOM nodes for p95+ pull requests. INP fell from 275–700+ milliseconds (ms) to just 40–80 ms for those big pull requests. By only showing what’s needed, the experience is much faster.
Further performance optimizations
To push performance even further, we tackled several major areas across our stack, each delivering meaningful wins for speed and responsiveness. By focusing on trimming unnecessary React re-renders and honing our state management, we cut down wasted computation, making UI updates noticeably faster and interactions smoother.
On the styling front, we swapped out heavy CSS selectors (e.g. :has(...)) and re-engineered drag and resize handling with GPU transforms, eliminating forced layouts and sluggishness and giving users a crisp, efficient interface for complex actions.
We also stepped up our monitoring game with interaction-level INP tracking, diff-size segmentation, and memory tagging, all surfaced in a Datadog dashboard. This continues to give our developers real-time, actionable metrics to spot and squash bottlenecks before they become issues.
On the server side, we optimized rendering to hydrate only visible diff lines. This slashed our time-to-interactive and keeps memory usage in check, ensuring that even huge pull requests feel fast and responsive on load.
Finally, with progressive diff loading and smart background fetches, users are now able to see and interact with content sooner. No more waiting for a massive number of diffs to finish loading.
All together, these targeted optimizations made our UI feel lighter, faster, and ready for anything our users throw at it.
Diff-initely better: The power of streamlined performance
This exciting journey to streamline the diff line architecture yielded substantial improvements in performance, efficiency and maintainability. By reducing unnecessary DOM nodes, simplifying our React component tree, and relocating complex state to conditionally rendered child components, we achieved faster rendering times and lower memory consumption. The adoption of more O(1) data access patterns and stricter rules for state management further optimized performance. This made our UI more responsive (faster INP!) and easier to reason with.
These measurable gains demonstrate that targeted refactoring, even within our large and mature codebase, can deliver meaningful benefits to all users—and that sometimes focusing on small, simple improvements can have the largest impact. To see the performance gains in action, go check out your open pull requests.
Software development is filled with repetitive tasks—managing issues, handling approvals, triggering CI/CD workflows, and more. But what if you could automate these types of tasks directly within GitHub Issues? That’s the promise of IssueOps, a methodology that turns GitHub Issues into a command center for automation.
Whether you’re a solo developer or part of an engineering team, IssueOps helps you streamline operations without ever leaving your repository.
In this article, I’ll explore the concept of IssueOps using state-machine terminology and strategies to help you work more efficiently on GitHub. After all, who doesn’t love automation?
What is IssueOps?
IssueOps is the practice of using GitHub Issues, GitHub Actions, and pull requests (PR) as an interface for automating workflows. Instead of switching between tools or manually triggering actions, you can use issue comments, labels, and state changes to kick off CI/CD pipelines, assign tasks, and even deploy applications.
Much like the various other *Ops paradigms (ChatOps, ClickOps, and so on), IssueOps is a collection of tools, workflows, and concepts that, when applied to GitHub Issues, can automate mundane, repetitive tasks. The flexibility and power of issues, along with their relationship to pull requests, create a near limitless number of possibilities, such as managing approvals and deployments. All of this can really help to simplify your workflows on GitHub. I’m speaking from personal experience here.
It’s important to note that IssueOps isn’t just a DevOps thing! Where DevOps offers a methodology to bring developers and operations into closer alignment, IssueOps is a workflow automation practice centered around GitHub Issues. IssueOps lets you run anything from complex CI/CD pipelines to a bed and breakfast reservation system. If you can interact with it via an API, there’s a good chance you can build it with IssueOps!
So, why use IssueOps?
There are lots of benefits to utilizing IssueOps. Here’s how it’s useful in practice:
It’s event driven, so you can automate the boring stuff: IssueOps lets you automate workflows directly from GitHub Issues and pull requests, turning everyday interactions—from kicking off a CI/CD pipeline and managing approvals to updating project boards—into powerful triggers for GitHub Actions.
It’s customizable, so you can tailor workflows to your needs: No two teams work the same way, and IssueOps is flexible enough to adapt. Whether you’re automating bug triage or triggering deployments, you can customize workflows based on event type and data provided.
It’s transparent, so you can keep a record: All actions taken on an issue are logged in its timeline, creating an easy-to-follow record of what happened and when.
It’s immutable, so you can audit whenever you need: Because IssueOps uses GitHub Issues and pull requests as a source of truth, every action leaves a record. No more chasing approvals in Slack or manually triggering workflows: IssueOps keeps everything structured, automated, and auditable right inside GitHub.
Defining IssueOps workflows and how they’re like finite-state machines
Most IssueOps workflows follow the same basic pattern:
A user opens an issue and provides information about a request
The issue is validated to ensure it contains the required information
The issue is submitted for processing
Approval is requested from an authorized user or team
The request is processed and the issue is closed
Suppose you’re an administrator of an organization and want to reduce the overhead of managing team members. In this instance, you could use IssueOps to build an automated membership request and approval process. Within a workflow like this, you’d have several core steps:
A user creates a request to be added to a team
The request is validated
The request is submitted for approval
An administrator approves or denies this request
The request is processed
If approved, the user is added to the team
If denied, the user is not added to the team
The user is notified of the outcome
When designing your own IssueOps workflows, it can be very helpful to think of them as a finite-state machine: a model for how objects move through a series of states in response to external events. Depending on certain rules defined within the state machine, a number of different actions can take place in response to state changes. If this is a little too complex, you can also think of it like a flow chart.
To apply this comparison to IssueOps, an issue is the object that is processed by a state machine. It changes state in response to events. As the object changes state, certain actions may be performed as part of a transition, provided any required conditions (guards) are met. Once an end state is reached, the issue can be closed.
This breaks down into a few key concepts:
State: A point in an object’s lifecycle that satisfies certain condition(s).
Event: An external occurrence that triggers a state change.
Transition: A link between two states that, when traversed by an object, will cause certain action(s) to be performed.
Action: An atomic task that is performed when a transition is taken.
Guard: A condition that is evaluated when a trigger event occurs. A transition is taken only if all associated guard condition(s) are met.
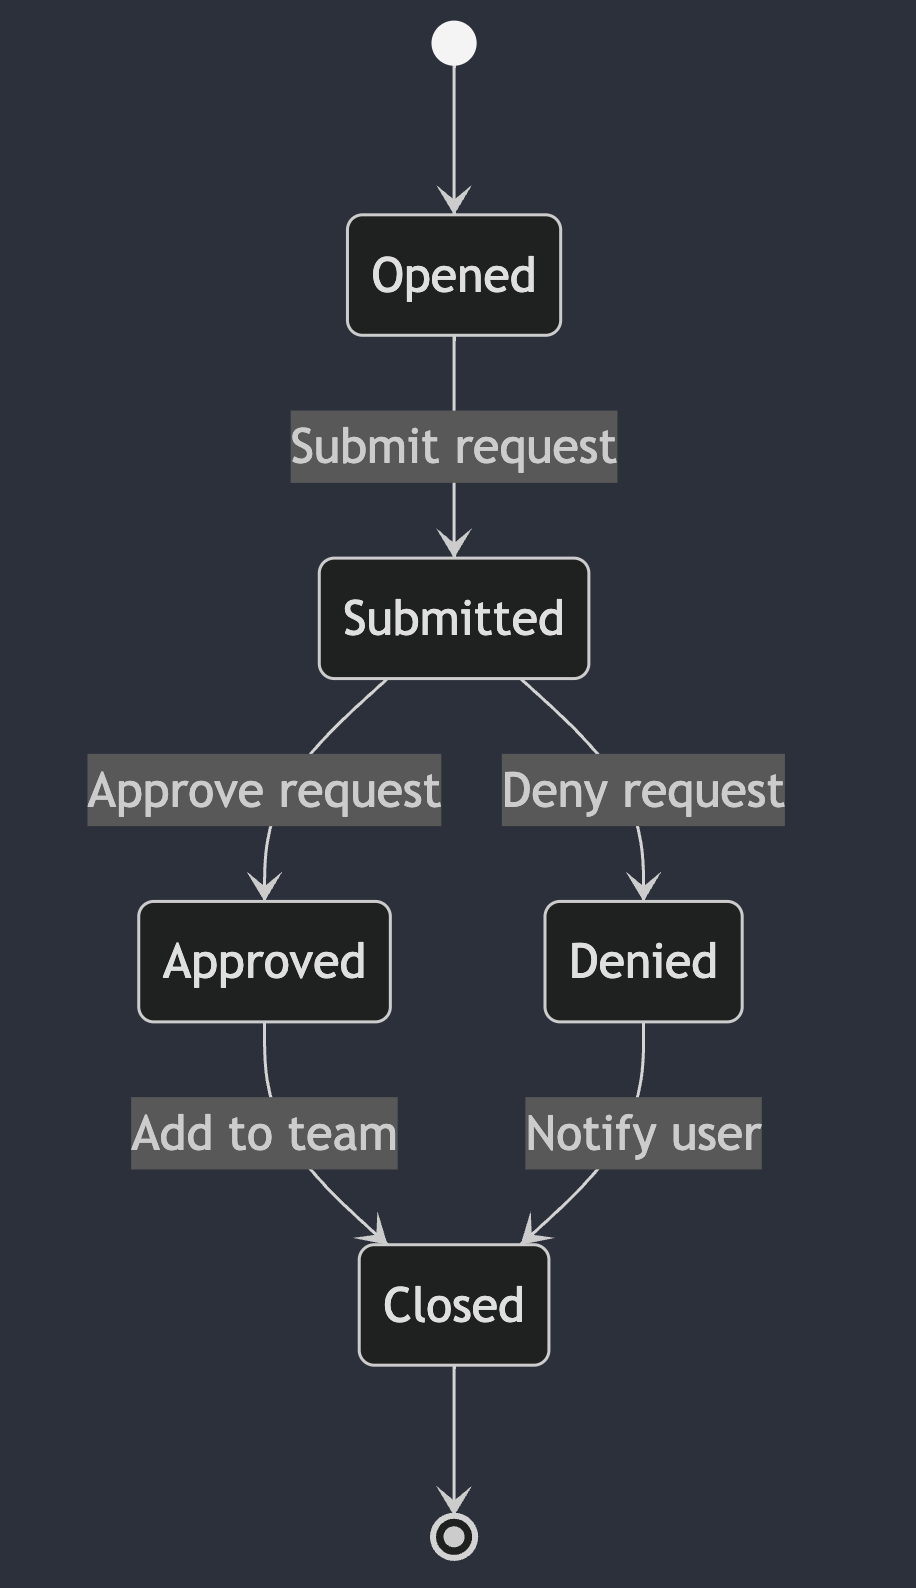
Here’s a simple state diagram for the example I discussed above.
Now, let’s dive into the state machine in more detail!
Key concepts behind state machines
The benefit of breaking your workflow down into these components is that you can look for edge cases, enforce conditions, and create a robust, reliable result.
States
Within a state machine, a state defines the current status of an object. As the object transitions through the state machine, it will change states in response to external events. When building IssueOps workflows, common states for issues include opened, submitted, approved, denied, and closed.
These should suffice as the core states to consider when building our workflows in our team membership example above.
Events
In a state machine, an event can be any form of interaction with the object and its current state. When building your own IssueOps, you should consider events from both the user and GitHub points of view.
In our team membership request example, there are several events that can trigger a change in state. The request can be created, submitted, approved, denied, or processed.
In this example, a user interacting with an issue—such as adding labels, commenting, or updating milestones—can also change its state. In GitHub Actions, there are many events that can trigger your workflows (see events that trigger workflows).
Here are a few interactions, or events, that would affect our example IssueOps workflow when it comes to managing team members:
Request
Event
State
Request is created
issues
opened
Request is approved
issue_comment
created
Request is denied
issue_comment
created
As you can see, the same GitHub workflow trigger can apply to multiple events in our state machine. Because of this, validation is key. Within your workflows, you should check both the type of event and the information provided by the user. In this case, we can conditionally trigger different workflow steps based on the content of the issue_comment event.
A transition is simply the change from one state to another. In our example, for instance, a transition occurs when someone opens an issue. When a request meets certain conditions, or guards, the change in state can take place. When the transition occurs, some actions or processing may take place, as well.
With our example workflow, you can think of the transitions themselves as the lines connecting different nodes in the state diagram. Or the lines connecting boxes in a flow chart.
Guards
Guards are conditions that must be verified before an event can trigger a transition to a different state. In our case, we know the following guards must be in place:
A request should not transition to an Approved state unless an administrator comments .approve on the issue.
A request should not transition to a Denied state unless an administrator comments .deny on the issue.
What about after the request is approved and the user is added to the team? This is referred to as an unguarded transition. There are no conditions that must be met, so the transition happens immediately!
Actions
Lastly, actions are specific tasks that are performed during a transition. They may affect the object itself, but this is not a requirement in our state machine. In our example, the following actions may take place at different times:
Administrators are notified that a request has been submitted
The user is added to the requested team
The user is notified of the outcome
A real-world example: Building a team membership workflow with IssueOps
Now that all of the explanation is out of the way, let’s dive into building our example! For reference, we’ll focus on the GitHub Actions workflows involved in building this automation. There are some additional repository and permissions settings involved that are discussed in more detail in these IssueOps docs.
Step 1: Issue form template
GitHub issue forms let you create standardized, formatted issues based on a set of form fields. Combined with the issue-ops/parser action, you can get reliable, machine-readable JSON from issue body Markdown. For our example, we are going to create a simple form that accepts a single input: the team where we want to add the user.
name: Team Membership Request
description: Submit a new membership request
title: New Team Membership Request
labels:
  - team-membership
body:
  - type: input
    id: team
    attributes:
      label: Team Name
      description: The team name you would like to join
      placeholder: my-team
    validations:
      required: true
When issues are created using this form, they will be parsed into JSON, which can then be passed to the rest of the IssueOps workflow.
{
  "team": "my-team"
}
Step 2: Issue validation
With a machine-readable issue body, we can run additional validation checks to ensure the information provided follows any rules we might have in place. For example, we can’t automatically add a user to a team if the team doesn’t exist yet! That is where the issue-ops/validator action comes into play. Using an issue form template and a custom validation script, we can confirm the existence of the team ahead of time.
module.exports = async (field) => {
  const { Octokit } = require('@octokit/rest')
  const core = require('@actions/core')

  const github = new Octokit({
    auth: core.getInput('github-token', { required: true })
  })

  try {
    // Check if the team exists
    core.info(`Checking if team '${field}' exists`)

    await github.rest.teams.getByName({
      org: process.env.GITHUB_REPOSITORY_OWNER ?? '',
      team_slug: field
    })

    core.info(`Team '${field}' exists`)
    return 'success'
  } catch (error) {
    if (error.status === 404) {
      // If the team does not exist, return an error message
      core.error(`Team '${field}' does not exist`)
      return `Team '${field}' does not exist`
    } else {
      // Otherwise, something else went wrong...
      throw error
    }
  }
}
When included in our IssueOps workflow, this adds any validation error(s) to the comment on the issue.
Step 3: Issue workflows
The main “entrypoint” of this workflow occurs when a user creates or edits their team membership request issue. This workflow should focus heavily on validating any user inputs! For example, what should happen if the user inputs a team that does not exist?
In our state machine, this workflow is responsible for handling everything up to the opened state. Any time an issue is created, edited, or updated, it will re-run validation to ensure the request is ready to be processed. In this case, an additional guard condition is introduced. Before the request can be submitted, the user must comment with .submit after validation has passed.
name: Process Issue Open/Edit

on:
  issues:
    types:
      - opened
      - edited
      - reopened

permissions:
  contents: read
  id-token: write
  issues: write

jobs:
  validate:
    name: Validate Request
    runs-on: ubuntu-latest

    # This job should only be run on issues with the `team-membership` label.
    if: ${{ contains(github.event.issue.labels.*.name, 'team-membership') }}

    steps:
      # This is required to ensure the issue form template and any validation
      # scripts are included in the workspace.
      - name: Checkout
        id: checkout
        uses: actions/checkout@v4

      # Since this workflow includes custom validation scripts, we need to
      # install Node.js and any dependencies.
      - name: Setup Node.js
        id: setup-node
        uses: actions/setup-node@v4

      # Install dependencies from `package.json`.
      - name: Install Dependencies
        id: install
        run: npm install

      # GitHub App authentication is required if you want to interact with any
      # resources outside the scope of the repository this workflow runs in.
      - name: Get GitHub App Token
        id: token
        uses: actions/create-github-app-token@v1
        with:
          app-id: ${{ vars.ISSUEOPS_APP_ID }}
          private-key: ${{ secrets.ISSUEOPS_APP_PRIVATE_KEY }}
          owner: ${{ github.repository_owner }}

      # Remove any labels and start fresh. This is important because the
      # issue may have been closed and reopened.
      - name: Remove Labels
        id: remove-label
        uses: issue-ops/labeler@v2
        with:
          action: remove
          github_token: ${{ steps.token.outputs.token }}
          labels: |
            validated
            approved
            denied
          issue_number: ${{ github.event.issue.number }}
          repository: ${{ github.repository }}

      # Parse the issue body into machine-readable JSON, so that it can be
      # processed by the rest of the workflow.
      - name: Parse Issue Body
        id: parse
        uses: issue-ops/parser@v4
        with:
          body: ${{ github.event.issue.body }}
          issue-form-template: team-membership.yml
          workspace: ${{ github.workspace }}

      # Validate early and often! Validation should be run any time an issue is
      # interacted with, to ensure that any changes to the issue body are valid.
      - name: Validate Request
        id: validate
        uses: issue-ops/validator@v3
        with:
          add-comment: true
          github-token: ${{ steps.token.outputs.token }}
          issue-form-template: team-membership.yml
          issue-number: ${{ github.event.issue.number }}
          parsed-issue-body: ${{ steps.parse.outputs.json }}
          workspace: ${{ github.workspace }}

      # If validation passes, add the validated label to the issue.
      - if: ${{ steps.validate.outputs.result == 'success' }}
        name: Add Validated Label
        id: add-label
        uses: issue-ops/labeler@v2
        with:
          action: add
          github_token: ${{ steps.token.outputs.token }}
          labels: |
            validated
          issue_number: ${{ github.event.issue.number }}
          repository: ${{ github.repository }}

      # The `issue-ops/validator` action will automatically notify the user that
      # the request was validated. However, you can optionally add instruction
      # on what to do next.
      - if: ${{ steps.validate.outputs.result == 'success' }}
        name: Notify User (Success)
        id: notify-success
        uses: peter-evans/create-or-update-comment@v4
        with:
          issue-number: ${{ github.event.issue.number }}
          body: |
            Hello! Your request has been validated successfully!

            Please comment with `.submit` to submit this request.
Step 4: Issue comment workflows
Once the issue is created, any further processing is triggered using issue comments—and this can be done with one workflow. However, to make things a bit easier to follow, we’ll break this into a few separate workflows.
Submit workflow
The first workflow handles the user submitting the request. The main task it performs is validating the issue body against the form template to ensure it hasn’t been modified.
name: Process Submit Comment

on:
  issue_comment:
    types:
      - created

permissions:
  contents: read
  id-token: write
  issues: write

jobs:
  submit:
    name: Submit Request
    runs-on: ubuntu-latest

    # This job should only be run when the following conditions are true:
    #
    # - A user comments `.submit` on the issue.
    # - The issue has the `team-membership` label.
    # - The issue has the `validated` label.
    # - The issue does not have the `approved` or `denied` labels.
    # - The issue is open.
    if: |
      startsWith(github.event.comment.body, '.submit') &&
      contains(github.event.issue.labels.*.name, 'team-membership') == true &&
      contains(github.event.issue.labels.*.name, 'approved') == false &&
      contains(github.event.issue.labels.*.name, 'denied') == false &&
      github.event.issue.state == 'open'

    steps:
      # First, we are going to re-run validation. This is important because
      # the issue body may have changed since the last time it was validated.

      # This is required to ensure the issue form template and any validation
      # scripts are included in the workspace.
      - name: Checkout
        id: checkout
        uses: actions/checkout@v4

      # Since this workflow includes custom validation scripts, we need to
      # install Node.js and any dependencies.
      - name: Setup Node.js
        id: setup-node
        uses: actions/setup-node@v4

      # Install dependencies from `package.json`.
      - name: Install Dependencies
        id: install
        run: npm install

      # GitHub App authentication is required if you want to interact with any
      # resources outside the scope of the repository this workflow runs in.
      - name: Get GitHub App Token
        id: token
        uses: actions/create-github-app-token@v1
        with:
          app-id: ${{ vars.ISSUEOPS_APP_ID }}
          private-key: ${{ secrets.ISSUEOPS_APP_PRIVATE_KEY }}
          owner: ${{ github.repository_owner }}

      # Remove the validated label. This will be re-added if validation passes.
      - name: Remove Validated Label
        id: remove-label
        uses: issue-ops/labeler@v2
        with:
          action: remove
          github_token: ${{ steps.token.outputs.token }}
          labels: |
            validated
          issue_number: ${{ github.event.issue.number }}
          repository: ${{ github.repository }}

      # Parse the issue body into machine-readable JSON, so that it can be
      # processed by the rest of the workflow.
      - name: Parse Issue Body
        id: parse
        uses: issue-ops/parser@v4
        with:
          body: ${{ github.event.issue.body }}
          issue-form-template: team-membership.yml
          workspace: ${{ github.workspace }}

      # Validate early and often! Validation should be run any time an issue is
      # interacted with, to ensure that any changes to the issue body are valid.
      - name: Validate Request
        id: validate
        uses: issue-ops/validator@v3
        with:
          add-comment: false # Don't add another validation comment.
          github-token: ${{ steps.token.outputs.token }}
          issue-form-template: team-membership.yml
          issue-number: ${{ github.event.issue.number }}
          parsed-issue-body: ${{ steps.parse.outputs.json }}
          workspace: ${{ github.workspace }}

      # If validation passed, add the validated and submitted labels to the issue.
      - if: ${{ steps.validate.outputs.result == 'success' }}
        name: Add Validated Label
        id: add-label
        uses: issue-ops/labeler@v2
        with:
          action: add
          github_token: ${{ steps.token.outputs.token }}
          labels: |
            validated
            submitted
          issue_number: ${{ github.event.issue.number }}
          repository: ${{ github.repository }}

      # If validation succeeded, alert the administrator team so they can
      # approve or deny the request.
      - if: ${{ steps.validate.outputs.result == 'success' }}
        name: Notify Admin (Success)
        id: notify-success
        uses: peter-evans/create-or-update-comment@v4
        with:
          issue-number: ${{ github.event.issue.number }}
          body: |
            👋 @issue-ops/admins! The request has been validated and is
            ready for your review. Please comment with `.approve` or `.deny`
            to approve or deny this request.
Deny workflow
If the request is denied, the user should be notified and the issue should close.
name: Process Denial Comment

on:
  issue_comment:
    types:
      - created

permissions:
  contents: read
  id-token: write
  issues: write

jobs:
  submit:
    name: Deny Request
    runs-on: ubuntu-latest

    # This job should only be run when the following conditions are true:
    #
    # - A user comments `.deny` on the issue.
    # - The issue has the `team-membership` label.
    # - The issue has the `validated` label.
    # - The issue has the `submitted` label.
    # - The issue does not have the `approved` or `denied` labels.
    # - The issue is open.
    if: |
      startsWith(github.event.comment.body, '.deny') &&
      contains(github.event.issue.labels.*.name, 'team-membership') == true &&
      contains(github.event.issue.labels.*.name, 'submitted') == true &&
      contains(github.event.issue.labels.*.name, 'validated') == true &&
      contains(github.event.issue.labels.*.name, 'approved') == false &&
      contains(github.event.issue.labels.*.name, 'denied') == false &&
      github.event.issue.state == 'open'

    steps:
      # This time, we do not need to re-run validation because the request is
      # being denied. It can just be closed.

      # However, we do need to confirm that the user who commented `.deny` is
      # a member of the administrator team.
      # GitHub App authentication is required if you want to interact with any
      # resources outside the scope of the repository this workflow runs in.
      - name: Get GitHub App Token
        id: token
        uses: actions/create-github-app-token@v1
        with:
          app-id: ${{ vars.ISSUEOPS_APP_ID }}
          private-key: ${{ secrets.ISSUEOPS_APP_PRIVATE_KEY }}
          owner: ${{ github.repository_owner }}

      # Check if the user who commented `.deny` is a member of the
      # administrator team.
      - name: Check Admin Membership
        id: check-admin
        uses: actions/github-script@v7
        with:
          github-token: ${{ steps.token.outputs.token }}
          script: |
            try {
              await github.rest.teams.getMembershipForUserInOrg({
                org: context.repo.owner,
                team_slug: 'admins',
                username: context.actor,
              })
              core.setOutput('member', 'true')
            } catch (error) {
              if (error.status === 404) {
                core.setOutput('member', 'false')
              }
              throw error
            }

      # If the user is not a member of the administrator team, exit the
      # workflow.
      - if: ${{ steps.check-admin.outputs.member == 'false' }}
        name: Exit
        run: exit 0

      # If the user is a member of the administrator team, add the denied label.
      - name: Add Denied Label
        id: add-label
        uses: issue-ops/labeler@v2
        with:
          action: add
          github_token: ${{ steps.token.outputs.token }}
          labels: |
            denied
          issue_number: ${{ github.event.issue.number }}
          repository: ${{ github.repository }}

      # Notify the user that the request was denied.
      - name: Notify User
        id: notify
        uses: peter-evans/create-or-update-comment@v4
        with:
          issue-number: ${{ github.event.issue.number }}
          body: |
            This request has been denied and will be closed.

      # Close the issue as not planned.
      - name: Close Issue
        id: close
        uses: actions/github-script@v7
        with:
          script: |
            await github.rest.issues.update({
              issue_number: ${{ github.event.issue.number }},
              owner: context.repo.owner,
              repo: context.repo.repo,
              state: 'closed',
              state_reason: 'not_planned'
            })
Approve workflow
Finally, we need to handle request approval. In this case, we need to add the user to the team, notify them, and close the issue.
name: Process Approval Comment

on:
  issue_comment:
    types:
      - created

permissions:
  contents: read
  id-token: write
  issues: write

jobs:
  submit:
    name: Approve Request
    runs-on: ubuntu-latest

    # This job should only be run when the following conditions are true:
    #
    # - A user comments `.approve` on the issue.
    # - The issue has the `team-membership` label.
    # - The issue has the `validated` label.
    # - The issue has the `submitted` label.
    # - The issue does not have the `approved` or `denied` labels.
    # - The issue is open.
    if: |
      startsWith(github.event.comment.body, '.approve') &&
      contains(github.event.issue.labels.*.name, 'team-membership') == true &&
      contains(github.event.issue.labels.*.name, 'submitted') == true &&
      contains(github.event.issue.labels.*.name, 'validated') == true &&
      contains(github.event.issue.labels.*.name, 'approved') == false &&
      contains(github.event.issue.labels.*.name, 'denied') == false &&
      github.event.issue.state == 'open'

    steps:
      # This time, we do not need to re-run validation because the request is
      # being approved. It can just be processed.

      # This is required to ensure the issue form template is included in the
      # workspace.
      - name: Checkout
        id: checkout
        uses: actions/checkout@v4

      # We do need to confirm that the user who commented `.approve` is a member
      # of the administrator team. GitHub App authentication is required if you
      # want to interact with any resources outside the scope of the repository
      # this workflow runs in.
      - name: Get GitHub App Token
        id: token
        uses: actions/create-github-app-token@v1
        with:
          app-id: ${{ vars.ISSUEOPS_APP_ID }}
          private-key: ${{ secrets.ISSUEOPS_APP_PRIVATE_KEY }}
          owner: ${{ github.repository_owner }}

      # Check if the user who commented `.approve` is a member of the
      # administrator team.
      - name: Check Admin Membership
        id: check-admin
        uses: actions/github-script@v7
        with:
          github-token: ${{ steps.token.outputs.token }}
          script: |
            try {
              await github.rest.teams.getMembershipForUserInOrg({
                org: context.repo.owner,
                team_slug: 'admins',
                username: context.actor,
              })
              core.setOutput('member', 'true')
            } catch (error) {
              if (error.status === 404) {
                core.setOutput('member', 'false')
              }
              throw error
            }

      # If the user is not a member of the administrator team, exit the
      # workflow.
      - if: ${{ steps.check-admin.outputs.member == 'false' }}
        name: Exit
        run: exit 0

      # Parse the issue body into machine-readable JSON, so that it can be
      # processed by the rest of the workflow.
      - name: Parse Issue body
        id: parse
        uses: issue-ops/parser@v4
        with:
          body: ${{ github.event.issue.body }}
          issue-form-template: team-membership.yml
          workspace: ${{ github.workspace }}

      - name: Add to Team
        id: add
        uses: actions/github-script@v7
        with:
          github-token: ${{ steps.token.outputs.token }}
          script: |
            const parsedIssue = JSON.parse('${{ steps.parse.outputs.json }}')

            await github.rest.teams.addOrUpdateMembershipForUserInOrg({
              org: context.repo.owner,
              team_slug: parsedIssue.team,
              username: '${{ github.event.issue.user.login }}',
              role: 'member'
            })

      - name: Notify User
        id: notify
        uses: peter-evans/create-or-update-comment@v4
        with:
          issue-number: ${{ github.event.issue.number }}
          body: |
            This request has been processed successfully!

      - name: Close Issue
        id: close
        uses: actions/github-script@v7
        with:
          script: |
            await github.rest.issues.update({
              issue_number: ${{ github.event.issue.number }},
              owner: context.repo.owner,
              repo: context.repo.repo,
              state: 'closed',
              state_reason: 'completed'
            })
Take this with you
And there you have it! With a handful of standardized workflows, you have an end-to-end, issue-driven process in place to manage team membership. This can be extended as far as you want, including support for removing users, auditing access, and more. With IssueOps, the sky is the limit!
Here’s the best thing about IssueOps: It brings another level of automation to a surface I’m constantly using—and that’s GitHub. By using issues and pull requests as control centers for workflows, teams can reduce friction, improve efficiency, and keep everything transparent. Whether you want to automate deployments, approvals, or bug triage, IssueOps makes it all possible, without ever leaving your repo.
In my experience, it’s always best to start small and experiment with what works best for you. With just a bit of time, you’ll see your workflows get smoother with every commit (I know I have). Happy coding! ✨
At GitHub, we use merge queue to merge hundreds of pull requests every day. Developing this feature and rolling it out internally did not happen overnight, but the journey was worth it—both because of how it has transformed the way we deploy changes to production at scale, but also how it has helped improve the velocity of customers too. Let’s take a look at how this feature was developed and how you can use it, too.
In 2020, engineers from across GitHub came together with a goal: improve the process for deploying and merging pull requests across the GitHub service, and specifically within our largest monorepo. This process was becoming overly complex to manage, required special GitHub-only logic in the codebase, and required developers to learn external tools, which meant the engineers developing for GitHub weren’t actually using GitHub in the same way as our customers.
To understand how we got to this point in 2020, it’s important to look even further back.
By 2016, nearly 1,000 pull requests were merging into our large monorepo every month. GitHub was growing both in the number of services deployed and in the number of changes shipping to those services. And because we deploy changes prior to merging them, we needed a more efficient way to group and deploy multiple pull requests at the same time. Our solution at this time was trains. A train was a special pull request that grouped together multiple pull requests (passengers) that would be tested, deployed, and eventually merged at the same time. A user (called a conductor) was responsible for handling most aspects of the process, such as starting a deployment of the train and handling conflicts that arose. Pipelines were added to help manage the rollout path. Both these systems (trains and pipelines) were only used on our largest monorepo and were implemented in our internal deployment system.
Trains helped improve velocity at first, but over time started to negatively impact developer satisfaction and increase the time to land a pull request. Our internal Developer Experience (DX) team regularly polls our developers to learn about pain points to help inform where to invest in improvements. These surveys consistently rated deployment as the most painful part of the developer’s daily experience, highlighting the complexity and friction involved with building and shepherding trains in particular. This qualitative data was backed by our quantitative metrics. These showed a steady increase in the time it took from pull request to shipped code.
Trains could also grow large, containing the changes of 15 pull requests. Large trains frequently “derailed” due to a deployment issue, conflicts, or the need for an engineer to remove their change. On painful occasions, developers could wait 8+ hours after joining a train for it to ship, only for it to be removed due to a conflict between two pull requests in the train.
Trains were also not used on every repository, meaning the developer experience varied significantly between different services. This led to confusion when engineers moved between services or contributed to services they didn’t own, which is fairly frequent due to our inner source model.
In short, our process was significantly impacting the productivity of our engineering teams—both in our large monorepo and service repositories.
Building a better solution for us and eventually for customers
By 2020, it was clear that our internal tools and processes for deploying and merging across our repositories were limiting our ability to land pull requests as often as we needed. Beyond just improving velocity, it became clear that our new solution needed to:
Improve the developer experience of shipping. Engineers wanted to express two simple intents: “I want to ship this change” and “I want to shift to other work;” the system should handle the rest.
Avoid having problematic pull requests impact everyone. Those causing conflicts or build failures should not impact all other pull requests waiting to merge. The throughput of the overall system should be favored over fairness to an individual pull request.
Be consistent and as automated as possible across our services and repositories. Manual toil by engineers should be removed wherever possible.
The merge queue project began as part of an overall effort within GitHub to improve availability and remove friction that was preventing developers from shipping at the frequency and level of quality that was needed. Initially, it was only focused on providing a solution for us, but was built with the expectation that it would eventually be made available to customers.
By mid-2021, a few small, internal repositories started testing merge queue, but moving our large monorepo would not happen until the next year for a few reasons.
For one, we could not stop deploying for days or weeks in order to swap systems. At every stage of the project we had to have a working system to ship changes. At a maximum, we could block deployments for an hour or so to run a test or transition. GitHub is remote-first and we have engineers throughout the world, so there are quieter times but never a free pass to take the system offline.
Changing the way thousands of developers deploy and merge changes also requires lots of communication to ensure teams are able to maintain velocity throughout the transition. Training 1,000 engineers on a new system overnight is difficult, to say the least.
By rolling out changes to the process in phases (and sometimes testing and rolling back changes early in the morning before most developers started working) we were able to slowly transition our large monorepo and all of our repositories responsible for production services onto merge queue by 2023.
How we use merge queue today
Merge queue has become the single entry point for shipping code changes at GitHub. It was designed and tested at scale, shipping 30,000+ pull requests with their associated 4.5 million CI runs, for GitHub.com before merge queue was made generally available.
For GitHub and our “deploy the merge process,” merge queue dynamically forms groups of pull requests that are candidates for deployment, kicks off builds and tests via GitHub Actions, and ensures our main branch is never updated to a failing commit by enforcing branch protection rules. Pull requests in the queue that conflict with one another are automatically detected and removed, with the queue automatically re-forming groups as needed.
Because merge queue is integrated into the pull request workflow (and does not require knowledge of special ChatOps commands, or use of labels or special syntax in comments to manage state), our developer experience is also greatly improved. Developers can add their pull request to the queue and, if they spot an issue with their change, leave the queue with a single click.
We can now ship larger groups without the pitfalls and frictions of trains. Trains (our old system) previously limited our ability to deploy more than 15 changes at once, but now we can now safely deploy 30 or more if needed.
Every month, over 500 engineers merge 2,500 pull requests into our large monorepo with merge queue, more than double the volume from a few years ago. The average wait time to ship a change has also been reduced by 33%. And it’s not just numbers that have improved. On one of our periodic developer satisfaction surveys, an engineer called merge queue “one of the best quality-of-life improvements to shipping changes that I’ve seen a GitHub!” It’s not a stretch to say that merge queue has transformed the way GitHub deploys changes to production at scale.
How to get started
Merge queue is available to public repositories on GitHub.com owned by organizations and to all repositories on GitHub Enterprise (Cloud or Server).
To learn more about merge queue and how it can help velocity and developer satisfaction on your busiest repositories, see our blog post, GitHub merge queue is generally available.
Ariel Deitcher (@mntlty) is a Senior Software Engineer at GitHub, working on Pull Requests and Merge Queue (beta). In this post, he shares the challenges he encountered finding his path to contributing to open source, what it was like contributing to open source at GitHub, and some of the lessons he learned.
Getting started with open source can be overwhelming
As a computer science graduate in 2011 and searching for my first tech job, I read that contributing to an open source project could help. It was a great way to build skills, make industry connections, and gain practical experience with a real-world problem. Perfect, I thought, I’ll just pick an open source project on this new website called GitHub, and, well, actually I wasn’t sure how to do that. Finding that “Goldilocks” project (where the size, language(s), domain, and community felt just right) was a lot harder than I thought, and I didn’t feel self-confident enough to make much progress. Overwhelmed, I decided the timing wasn’t right but resolved to try again someday.
It bugged me that the contribution graph on my GitHub profile remained stubbornly empty, as all the code I had committed lived in private repositories. That changed in 2016 when contributions to private repositories could be shown on my profile, but my contributions to open source had not. Between my family, work, life, and the explosive growth in projects to choose from, making that first contribution to open source felt more daunting than ever.
The opportunity to contribute to open source at GitHub
Fast forward to 2021. I read Working in Public: The Making and Maintenance of Open Source Software by Nadia Eghbal while interviewing at GitHub. I was especially captivated by the Stadium model of open source projects, where a small number of maintainers and occasional contributors are vastly outnumbered by a project’s users. This aligned with my mental model of open source projects, where a few performers on a digital stage would conjure feats of coding wizardry. I could only imagine how vulnerable working in public could be, and hoped it would feel less intimidating working at GitHub.
I joined the GitHub team building Merge Queue (beta), a feature which helps users coordinate their merges to a protected branch, ensures that changes are up to date, and that all required checks pass before automatically merging a pull request. Early on, I shared my long-held goal of contributing code to an open source project with my manager, and discussed the GitHub CLI, an open source tool written in Go which lets users interact with GitHub from the command line, as a possible candidate.
While building Merge Queue, our team carefully integrated it with GitHub’s many APIs and tools, checking each one for compatibility and correctness. Testing different scenarios of merging a pull request with the GitHub CLI, I saw that once a Merge Queue was required, running the CLI command gh pr merge would fail in most cases. The Merge Queue was correctly preventing direct merges to its protected branch, and so I began scoping out what changes the CLI might need to support Merge Queue.
As I didn’t have write access to the CLI repository, I forked it, started a new Codespace, and spent some time getting familiar with the CLI’s contributing guidelines and code. Wanting to minimize my changes, I targeted a few places in the merge command to modify. When I was ready, I pushed a commit to my fork and opened a pull request to share with the CLI maintainers. I expected that I would provide support but defer to them for the final implementation.
In reviewing my pull request with the CLI maintainers, it quickly became clear that my changes were hard to reason about. The merge command had accumulated sufficient technical debt that adding more complexity to it was risky. The team asked if I could refactor the merge command in an initial pull request and follow up with a subsequent pull request for the Merge Queue changes after the first was merged. What I had thought would be a rough guide of changes for the CLI maintainers was, in fact, the opportunity I had been looking for to contribute to open source at GitHub. I confirmed that my manager was onboard with this increased commitment, and was ready to get started.
Refactoring the merge command and adding Merge Queue support
I set out to refactor the merge command with a focus on simplicity, readability, and returning early over deeply nested conditionals. The existing test coverage gave me a confidence boost as I began stepping through the code, copying each section into a separate file for later reference, and wrote comments which I felt captured the intent of the removed section. I then grouped related Git and API operations, consolidated common code into appropriately named functions and variables, trimmed unreachable code paths, created a MergeContext struct to encapsulate state, and leaned into Go’s explicit error returns – all of which gave the code a more linear and consistent structure.
func mergeRun(opts *MergeOptions) error {
    ctx, err := NewMergeContext(opts)
    if err != nil {
        return err
    }

    // no further action is possible when disabling auto merge
    if opts.AutoMergeDisable {
        return ctx.disableAutoMerge()
    }

    ctx.warnIfDiverged()

    if err := ctx.canMerge(); err != nil {
        return err
    }

    if err := ctx.merge(); err != nil {
        return err
    }

    if err := ctx.deleteLocalBranch(); err != nil {
        return err
    }

    if err := ctx.deleteRemoteBranch(); err != nil {
        return err
    }

    return nil
}
When I was finished, I opened a pull request from my fork to the CLI repository, and was blown away by how supportive the code review process was. After a few rounds of feedback, my code was merged and ready to ship in the next release. I was an open source contributor at GitHub!
Returning to my fork, my original Merge Queue changes were now completely out of date. In fact, much of the code I had on my branch no longer existed on the CLI’s trunk branch. Fortunately, I was now intimately familiar with the merge command and was able to make the Merge Queue changes and tests in a subsequent pull request quickly and with confidence.
Lessons learned
Looking back, I learned that searching for the right open source project on my own, trying to create time outside of work, and context switching from my existing projects were obstacles I could not overcome. Instead, the key for me was to find an open source project that was important to what I was already working on, and that I was accountable for. If this sounds familiar, consider asking your manager if you can devote some time to work on an issue in an open source project that you or your team rely on. It’s much easier to get started with an open source project you know and can align with work you’re already committed to. I recognize how fortunate I was to be in the right place at the right time, and with the right support from my manager, but it wasn’t easy.
Many people I know struggle with impostor syndrome, and working in public made me even more aware of mine. I am learning to accept that even though my commits aren’t perfect, and that I’m afraid of being judged for creating bugs like this regression, which will be discoverable forever, I should still contribute. Despite these challenges, I enjoy picking up new issues in the CLI labeled “help wanted (contributions welcome)” whenever I can, and hope you will too!
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.