All posts by Aruna Govindaraju

Measuring and improving search quality with Amazon OpenSearch Service

Post Syndicated from Aruna Govindaraju original https://aws.amazon.com/blogs/big-data/measuring-and-improving-search-quality-with-amazon-opensearch-service/

Search is the front door of many applications, yet most teams struggle to answer a deceptively simple question: “Is my search actually returning relevant results?” Query logs tell you what users typed, not what they saw, what they selected, or why they left. When search feels broken, the culprit is rarely the engine. It’s the lack of deliberate signal collection, measurement, and a feedback loop to act on it.

You can close this gap on Amazon OpenSearch Service using User Behavior Insights (UBI), an open schema standard for capturing search behavior, and Search Relevance Workbench (SRW), a toolkit for measuring and evaluating search quality. Your application generates the UBI-formatted records. Together, UBI and SRW give you a repeatable framework: collect signals, turn them into relevance judgments, and validate every change before it ships.

In this post, we show you how to capture UBI data on an Amazon OpenSearch Service domain and use those signals to evaluate search quality. This is the first post in a two-part series. We build the foundation here, and Part 2 covers automating the workflow end to end.

The challenge: You can’t improve what you can’t measure

Consider a shopper searching for “handbag” on an ecommerce site. The catalog has 16 products (tote bags, duffel bags, laptop bags), but every title only says “bag.” The search returns zero results. Most shoppers leave. A patient one retries with “bag” and finds what they were looking for.

Your server log recorded that first query as a clean sub-second response: no error, no alert, no signal. What it missed entirely was a customer with purchase intent. That customer hit a vocabulary gap between how they search and how you write your catalog. Zoom out and apply this lens to misspelled queries, poor handling of long-tail searches, and abandoned sessions. The blind spot is larger than you think.

There’s a second problem: click signals are position biased. Users select the first result far more than the fifth, regardless of relevance, so raw click counts reflect where results appeared, not whether they deserved to be there. Any judgment derived from clicks must correct for this bias. We return to it when generating judgments.

Capturing behavioral data with UBI

UBI defines two indices. The ubi_queries index holds one record per executed query: the text the user typed, the full query that ran (filters and facets included), and the IDs of the documents returned. The ubi_events index holds every subsequent user action: impressions, hovers, clicks, add-to-carts, each stamped with the result position and the product’s business identifier (object_id). A shared query_id links every event back to the query that triggered it. Two additional identifiers complete the picture: client_id tracks the browser across visits, and session_id scopes events to a single visit.

A query record captures what the user asked and which document IDs the engine returned, including zero-result cases like the handbag search, which appears as a record with an empty result list. Here’s the shopper’s follow-up search for “bag”:

{
  "query_id": "1bf736d4-d673-4763-9193-4bc8a2282115",
  "client_id": "9a9968ac-664b-42d7-9a9e-96f412b5ab49",
  "user_query": "bag",
  "query": "{"multi_match": {"query": "bag", "fields": ["title", "description", "category", "brand"]}}",
  "query_response_hit_ids": [
    "3760170840499",
    "8400000000042"
  ],
  "timestamp": "2026-07-23T07:53:35.264Z",
  "application": "retail-shop"
}

The UBI queries schema reference documents the complete query schema, including the mandatory attributes.

The event record captures what the user did next. For each result rendered, emit an impression event. When the user selects a result, emit a click event. Here is the impression event for the first result of the bag search:

{
  "action_name": "impression",
  "query_id": "1bf736d4-d673-4763-9193-4bc8a2282115",
  "client_id": "9a9968ac-664b-42d7-9a9e-96f412b5ab49",
  "session_id": "0f2e6f2a-8f4e-4f60-9f6e-2a1b3c4d5e6f",
  "user_query": "bag",
  "timestamp": "2026-07-23T07:53:41.112Z",
  "event_attributes": {
    "position": {
      "ordinal": 1
    },
    "object": {
      "object_id": "3760170840499",
      "object_id_field": "object_id"
    }
  }
}

event_attributes also accepts custom fields of your own alongside the standard position and object structures. The action_name attribute is critical: The judgment model you use later consumes only impression and click events. Treat a paginated results page as the same logical query: reuse the query_id and record absolute positions. The UBI events schema reference documents the complete event schema.

Collecting UBI data on Amazon OpenSearch Service

Behavioral data (what results ranked, what users saw, what they selected) exists only in the application layer. Your application owns the records, and Amazon OpenSearch Ingestion (OSI), a fully managed, serverless data collector powered by Data Prepper, provides the managed delivery path. Your application sends the records as SigV4-signed HTTP POST requests to the OSI pipeline endpoints. Route browser events through your backend for signing. One thing to understand before you write any code: Your application generates and owns the query_id attribute. The application creates the ID when it runs a search and stamps it on every subsequent event the user produces, until the user issues a new search or the session ends.

Prerequisites

To follow along, you need an Amazon OpenSearch Service domain running OpenSearch 3.5 or later with the OpenSearch UI application, permissions to create OpenSearch Ingestion pipelines with an AWS Identity and Access Management (IAM) pipeline role, and a search application you can instrument to emit behavioral records.

Create the UBI indices

Before you start collecting user metrics, you need the two indices in place with the right mappings. Field types matter here: query_id as keyword supports exact joins between queries and events, timestamp as date supports time-range queries, and event_attributes as dynamic means you can extend events with custom fields without schema changes.

Create ubi_queries first in Dev Tools. It holds the query-side records. We abbreviated the mappings here. Refer to the published queries-mapping.json file for the complete version:

PUT ubi_queries
{
  "mappings": {
    "properties": {
      "query_id": { "type": "keyword" },
      "client_id": { "type": "keyword" },
      "user_query": { "type": "keyword" },
      "query_response_hit_ids": { "type": "keyword" },
      "timestamp": {
        "type": "date",
        "format": "strict_date_time"
      },
      "application": { "type": "keyword" }
    }
  }
}

Then create ubi_events. It holds every user action that follows (refer to the full events-mapping.json file):

PUT ubi_events
{
  "mappings": {
    "properties": {
      "query_id": { "type": "keyword", "ignore_above": 100 },
      "action_name": { "type": "keyword", "ignore_above": 100 },
      "client_id": { "type": "keyword", "ignore_above": 100 },
      "session_id": { "type": "keyword", "ignore_above": 100 },
      "user_query": { "type": "keyword" },
      "timestamp": {
        "type": "date",
        "format": "strict_date_time"
      },
      "event_attributes": {
        "dynamic": true,
        "properties": {
          "position": {
            "properties": {
              "ordinal": { "type": "integer" }
            }
          },
          "object": {
            "properties": {
              "object_id": { "type": "keyword" },
              "object_id_field": { "type": "keyword" }
            }
          }
        }
      }
    }
  }
}

With both indices created, the next step is routing data into them. You can deliver UBI data to your domain in several ways. This post uses OSI pipelines, shown end to end in the diagram that follows the setup.

Set up the OSI pipelines

Create two OSI pipelines: one for queries and another for events. Each pipeline exposes an HTTP source endpoint that your application writes to (shown on each pipeline’s console page) and sinks data to the corresponding index. The following configuration defines the events pipeline:

version: '2'
ubi-events:
  source:
    http:
      path: /ubi/events
      max_request_length: 10mb
  processor:
    - date:
        from_time_received: true
  sink:
    - opensearch:
        hosts: ["https://<domain-endpoint>"]
        aws:
          serverless: false
          region: <region>
          sts_role_arn: <pipeline-role-arn>
        index_type: custom
        index: ubi_events
    - s3:
        aws:
          region: <region>
          sts_role_arn: <pipeline-role-arn>
        object_key:
          path_prefix: 'ubi_events/%{yyyy}/%{MM}/%{dd}'
        bucket: <bucket-name>
        threshold:
          maximum_size: 50mb
          event_collect_timeout: 60s
        codec:
          ndjson:

Note: the queries pipeline follows the same pattern, with /ubi/queries as the path and ubi_queries as the sink index and S3 prefix. Create the pipeline role yourself or let OpenSearch Ingestion create it. If your domain uses fine-grained access control, also map the pipeline role to a backend role so the domain accepts the pipeline’s writes. Refer to the tutorial Collecting UBI-formatted data in Amazon OpenSearch Service for detailed steps.

With the pipelines running, your application can start sending data. The following diagram illustrates the end-to-end flow:
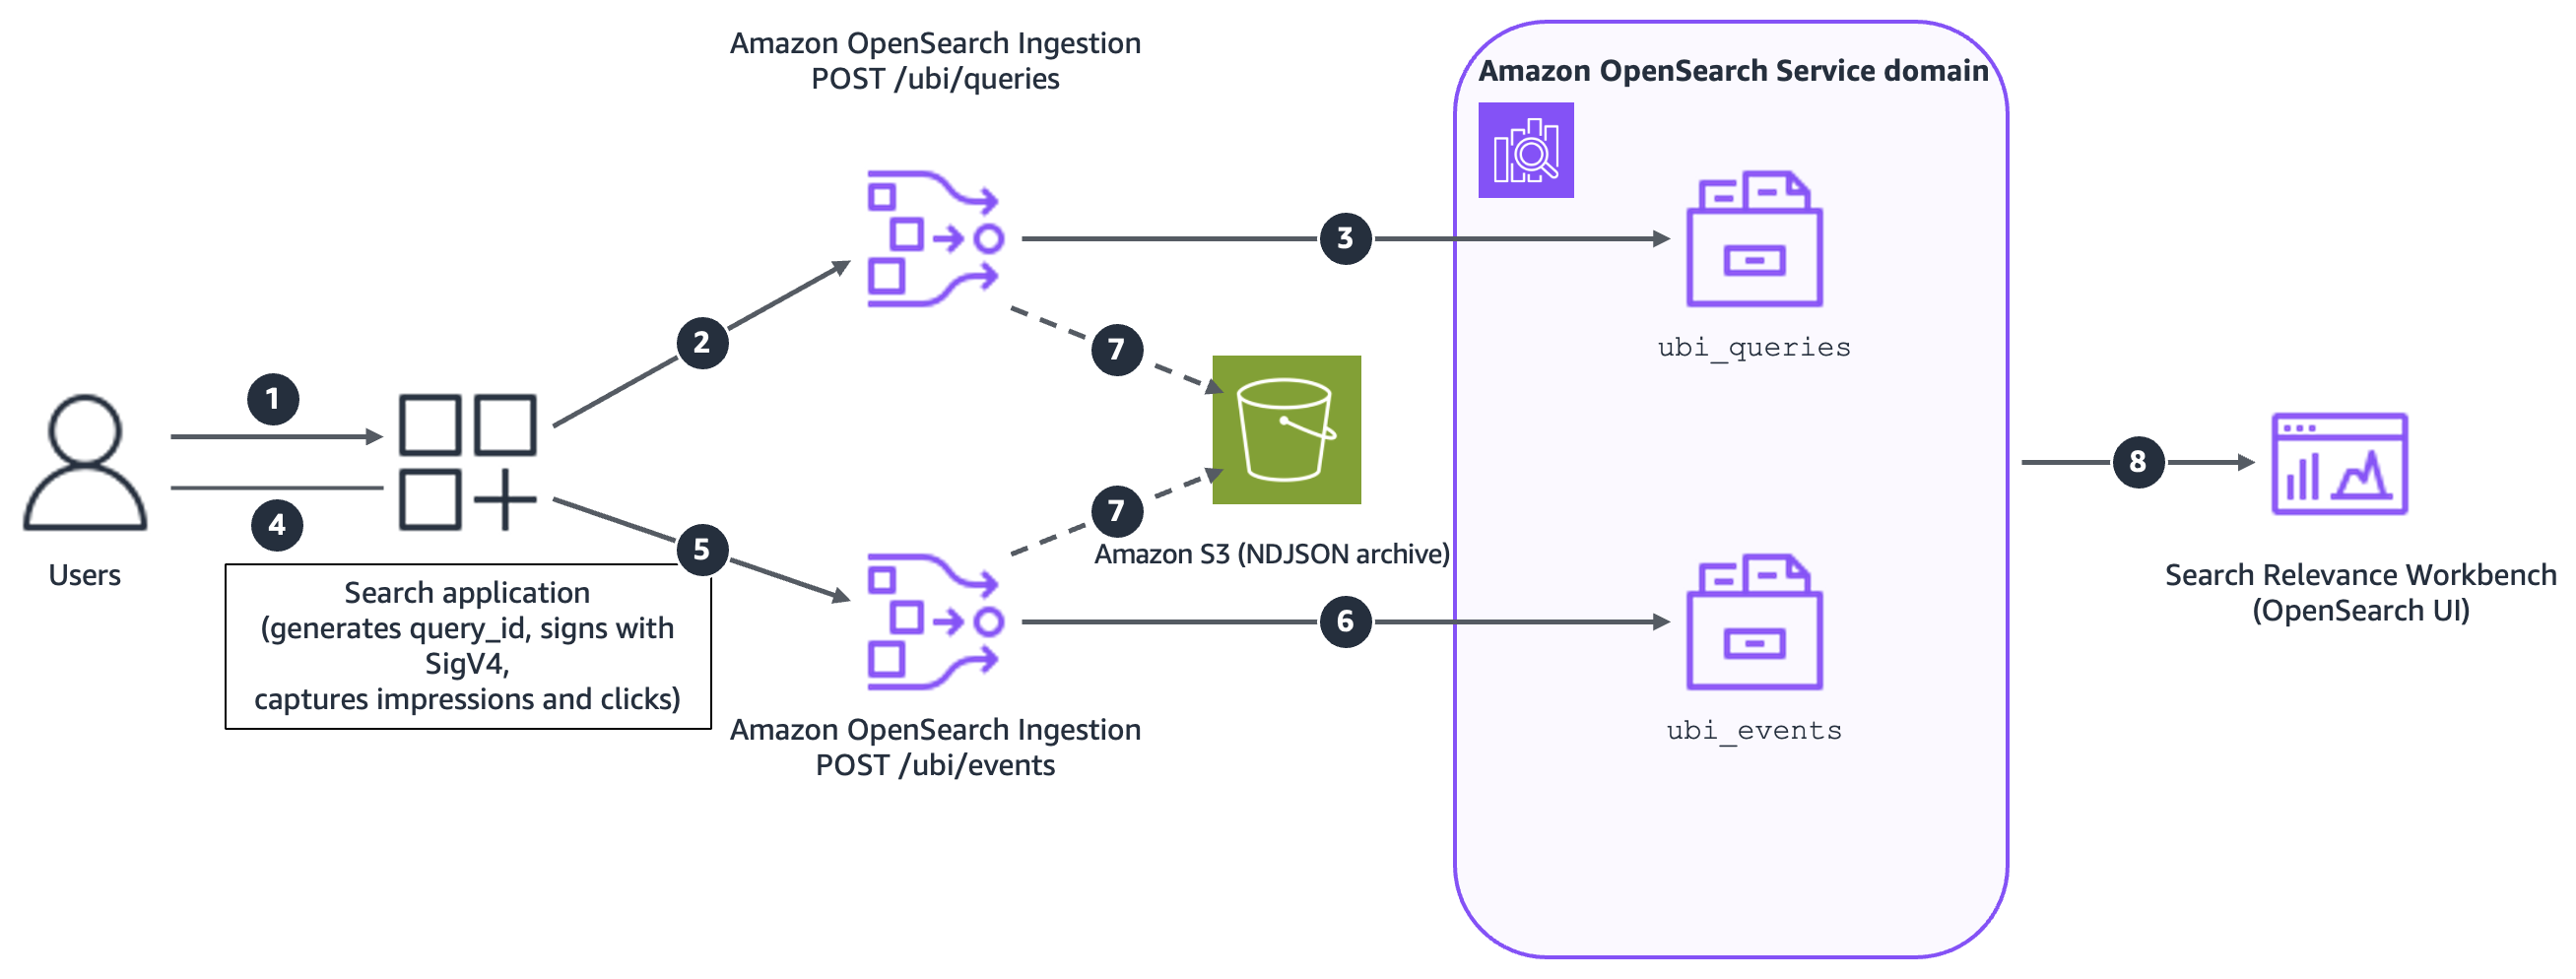
UBI collection flow from the search application through OpenSearch Ingestion into the ubi_queries and ubi_events indices

Figure 1: The UBI collection pattern on Amazon OpenSearch Service

The workflow consists of the following steps:

  1. Users interact with your search application.
  2. The application sends signed query records to the OSI HTTP endpoint.
  3. OSI writes queries to the ubi_queries index.
  4. Users interact with the results, viewing and selecting documents.
  5. The application sends signed event records, carrying the same query_id, to the OSI HTTP endpoint.
  6. OSI writes events to the ubi_events index.
  7. Optionally, both pipelines archive records to Amazon Simple Storage Service (Amazon S3).
  8. Search Relevance Workbench (OpenSearch UI) works with the collected data in the ubi_queries and ubi_events indices.

Note: if you’re already collecting site analytics through an existing third-party tool, you don’t need to replace it. Map your search-related events (queries, clicks, and conversions) into the UBI schema and store them in OpenSearch. That’s enough to unlock the out-of-the-box evaluation framework, implicit judgment generation, and the full SRW metrics pipeline, without defining a single custom metric from scratch.

Visualize the data collected

After the UBI behavior metrics start to trickle in, you can review the data in the Discover tab on the OpenSearch UI dashboard. Filtering ubi_queries for empty result lists ranks your vocabulary gaps. You can also visualize the data collected through the sample User Behavior Insights (UBI) dashboards in OpenSearch.
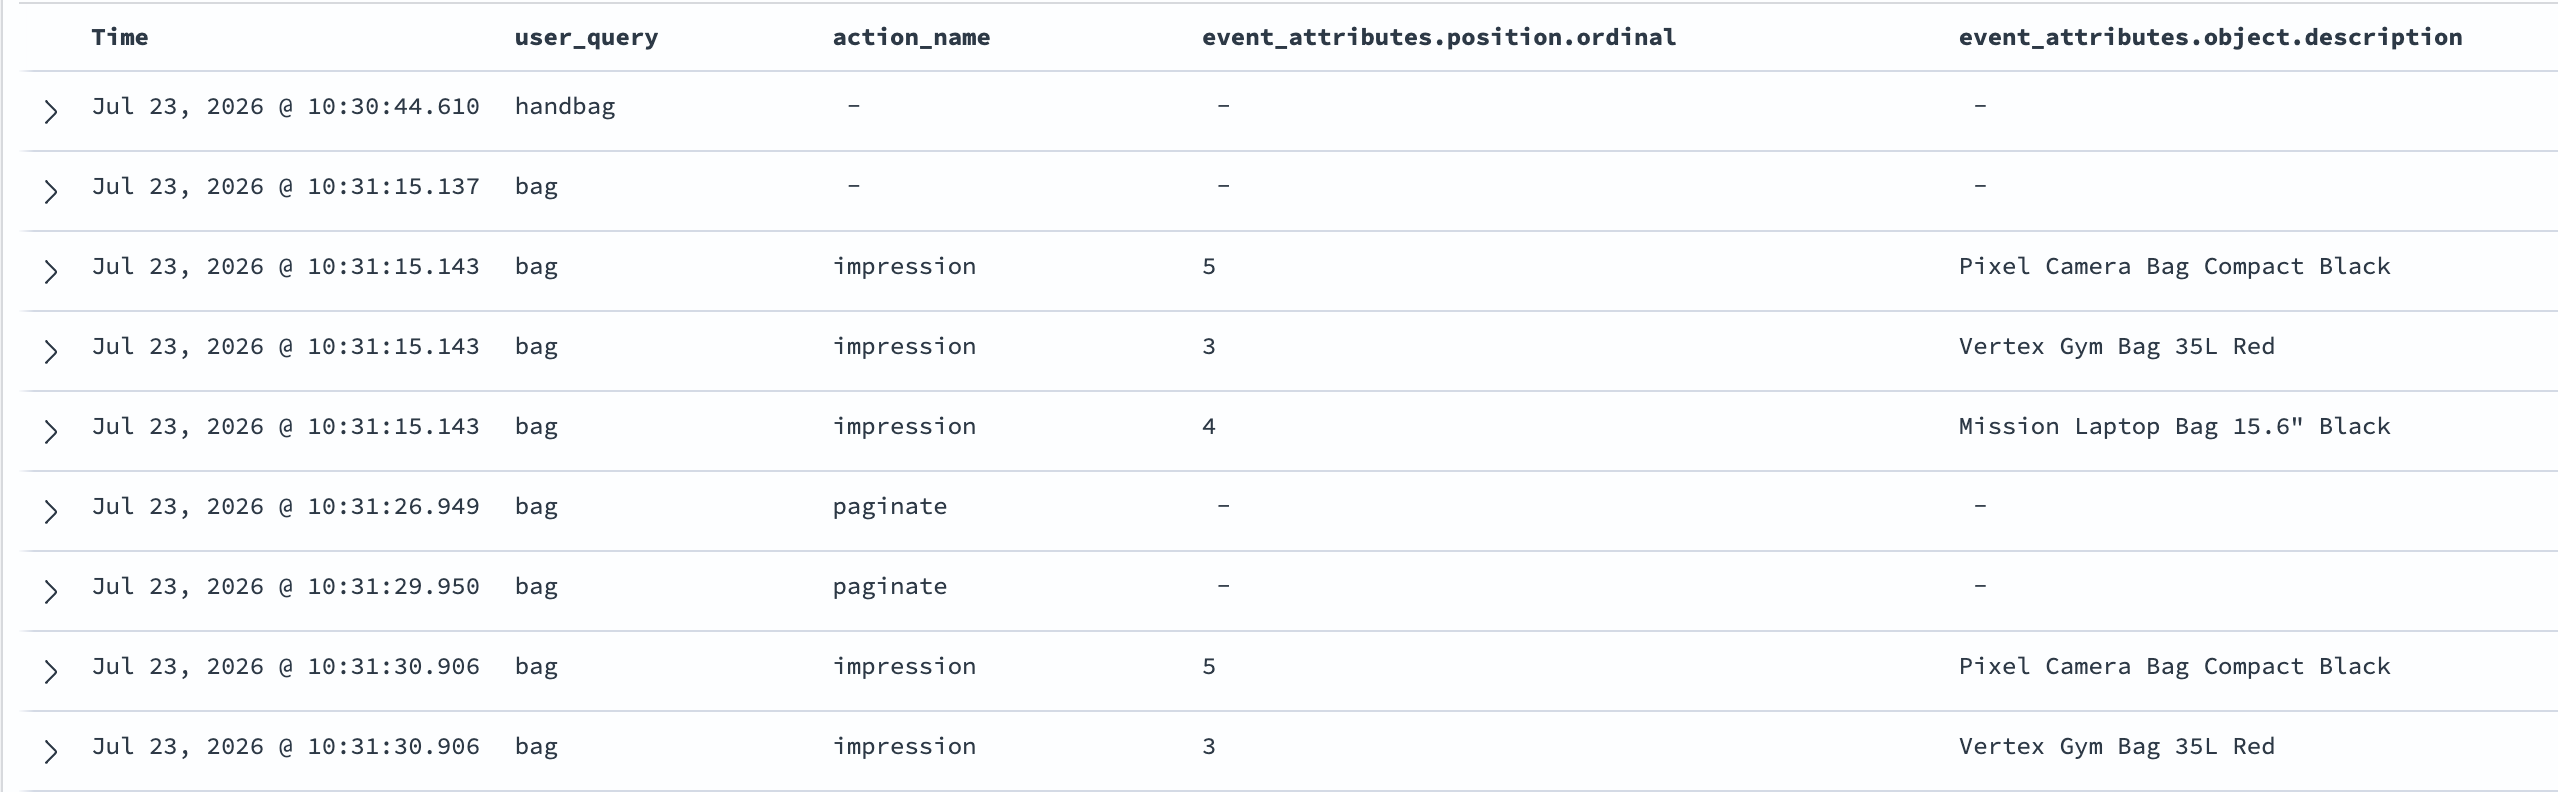
OpenSearch Discover view of UBI records for the zero-result handbag query and the follow-up bag query

Figure 2: UBI records in Discover, showing the zero-result handbag query and the follow-up bag query with its impressions and pagination events

With data flowing into your indices, keep these things in mind as you scale to production:

  • Keep telemetry off the search critical path – Queue records and forward them asynchronously. Losing a fraction of behavioral data is statistically harmless. Blocking users isn’t.
  • Manage volume deliberately – Batch impression events, and if you sample, sample whole queries rather than individual events to preserve the click-through ratios that drive judgments.
  • Isolate analytical load for larger deployments – Route pipelines to a separate analysis domain with the same engine version, mappings, and analyzers as production. This keeps behavioral writes from touching live search latency.
  • Plan for retention and integrity – Register the UBI mappings as an index template and apply an Index State Management (ISM) retention policy as your indices grow. You should validate and rate-limit the event write path, and cover query text and client identifiers with your data retention policy.

Evaluating search quality with Search Relevance Workbench

With ubi_queries and ubi_events collecting data, you now have the signals needed to evaluate search quality. Search Relevance Workbench, generally available in the OpenSearch UI from Amazon OpenSearch Service 3.5, turns those signals into structured experiments: comparing query configurations, scoring results against relevance judgments, and surfacing metrics that guide iterative tuning.
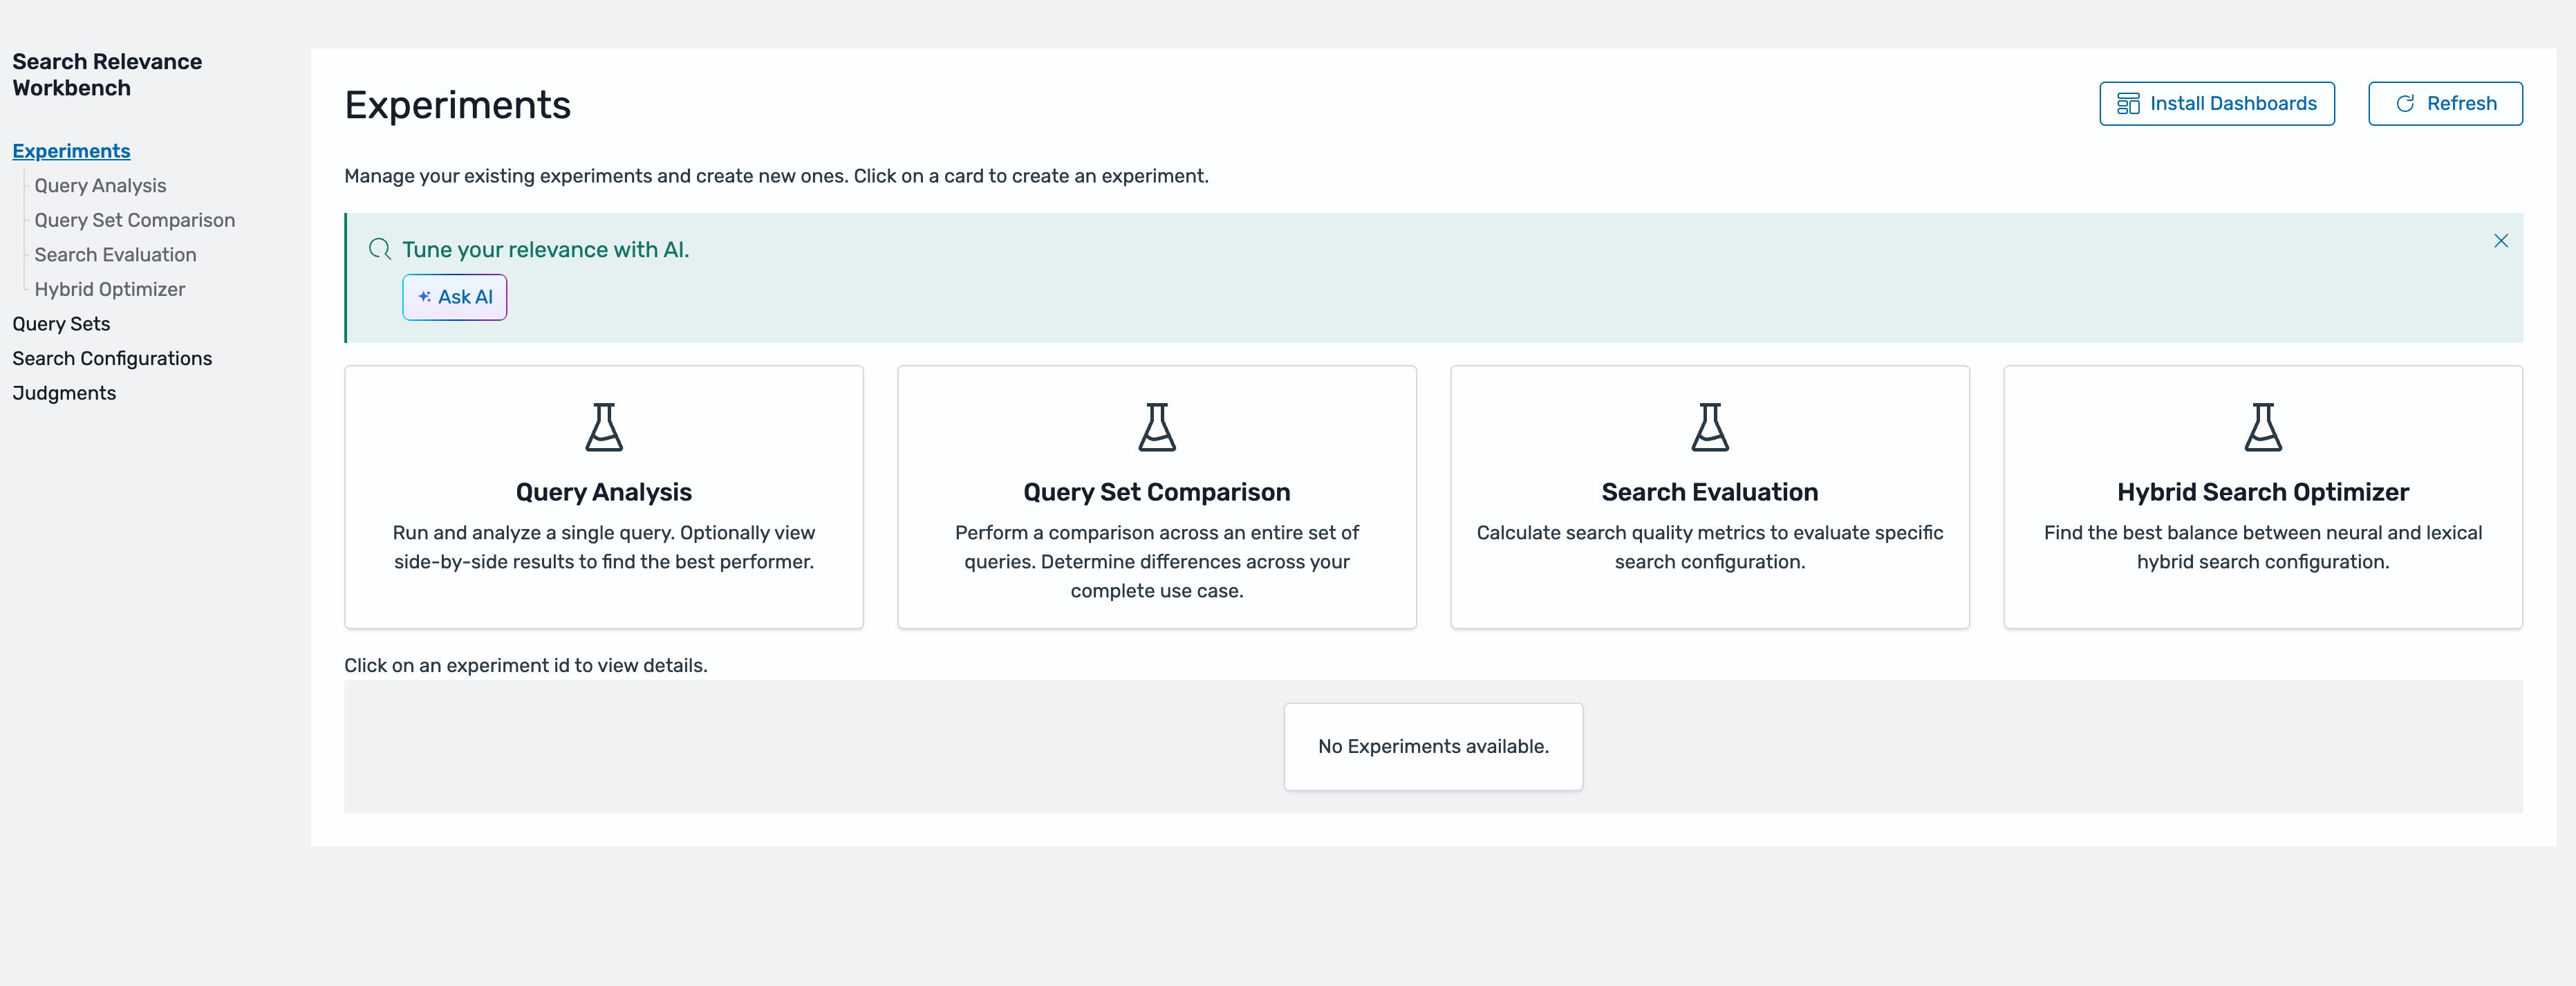
The Search Relevance Workbench home screen in the OpenSearch UI

Figure 3: Search Relevance Workbench in the OpenSearch UI

SRW experiments rely on three components. You set them up once, then reuse them across every experiment you run: a query set (the fixed queries you evaluate against), search configurations (the query structures you want to compare), and a judgment list (the relevance ground truth). The following sections walk through each one.

Step 1: Create a query set

A query set is the fixed collection of queries you evaluate against. Keeping it fixed makes results comparable across experiments. Effective query sets reflect real traffic, not intuition. You can seed one from your top queries, a random sample, or a hand-picked mix that includes long-tail and low-performing queries. Alternatively, SRW can sample directly from ubi_queries using Probability-Proportional-to-Size (PPS) sampling, which selects queries in proportion to how often users issue them. This approach represents frequent queries like “bag”, so your metrics reflect search quality as users experience it.
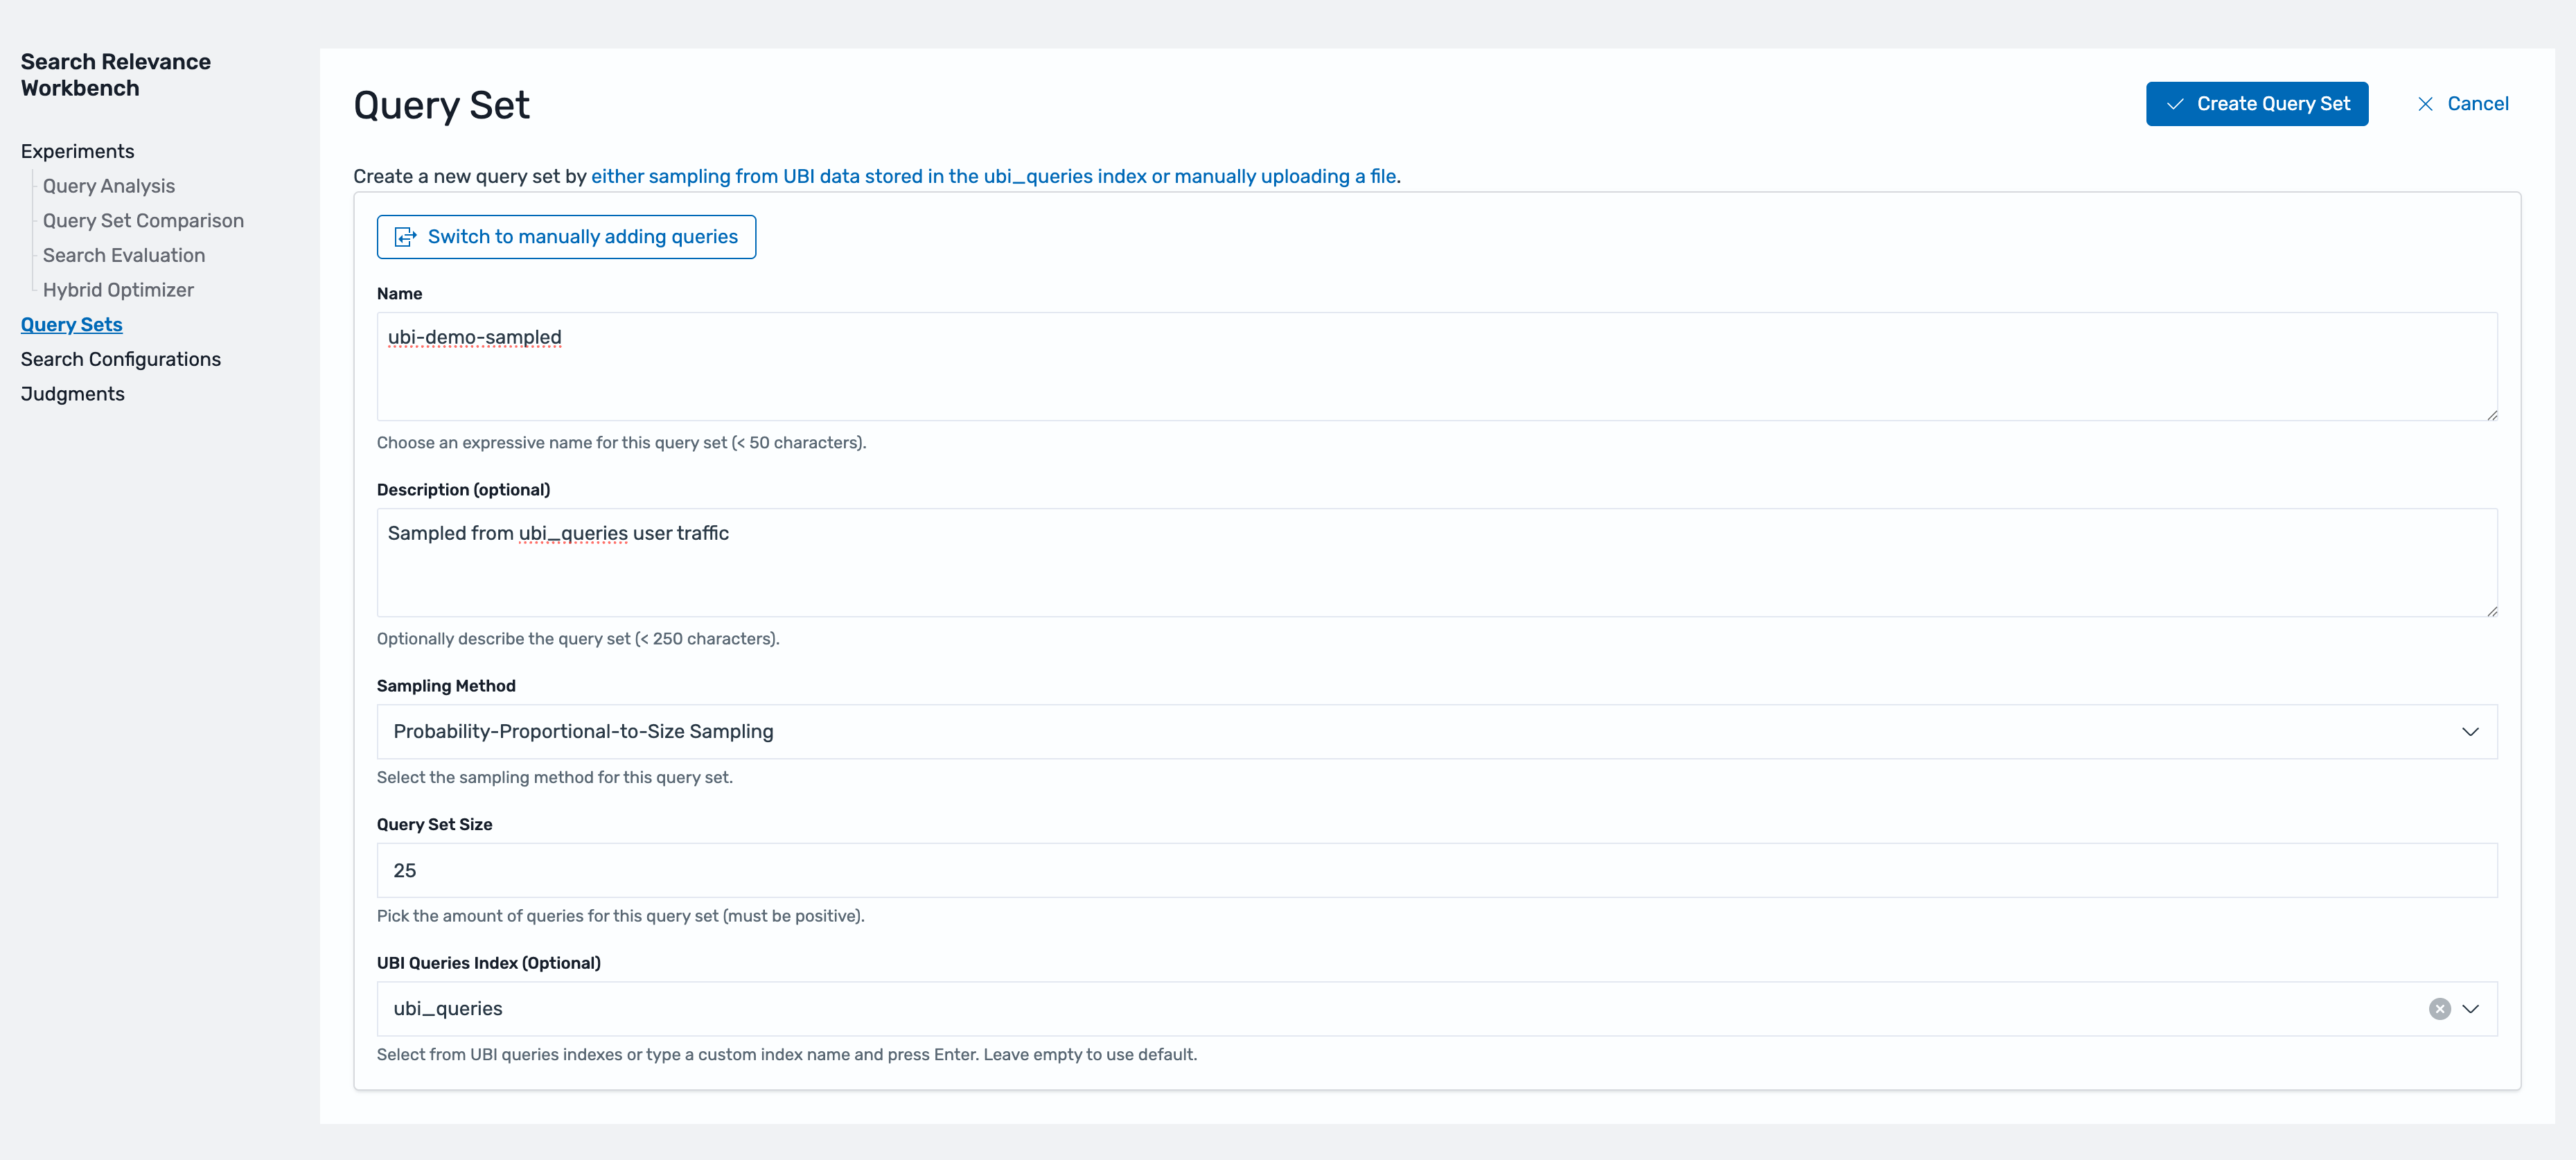
Query set creation screen sampling queries from real traffic in the ubi_queries index

Figure 4: Creating a query set sampled from real traffic in ubi_queries

Step 2: Define search configurations

A search configuration defines how a search executes: the index, the query structure, and a %SearchText% placeholder that SRW replaces with each query in your set. Creating two configurations and running them against the same query set and judgment list is how you validate a change before any user sees it.

As an example, here we define two configurations: a baseline multi_match query (retail_query) and a variant that boosts title matches (retail_boosted_query), so we can measure whether the boost actually helps ranking.

retail_query retail_boosted_query
{
  "query": {
    "multi_match": {
      "query": "%SearchText%",
      "fields": [
        "title",
        "description",
        "category",
        "brand"
      ]
    }
  }
}
{
  "query": {
    "multi_match": {
      "query": "%SearchText%",
      "fields": [
        "title^2",
        "description",
        "category",
        "brand"
      ]
    }
  }
}

Configurations go beyond query variants: a candidate can be an entirely different retrieval strategy, like hybrid search combining keyword and neural retrieval. You can use judgments to rate query-document pairs independently of your retrieval approach. You can test a semantic or hybrid approach offline against your existing traffic before shipping it.

Step 3: Create the judgment list

A judgment is a relevance rating for a query-document pair: the ground truth that quality metrics measure against. You can create judgments that are explicit (from stakeholders or a large language model acting as judge), imported, or implicit (derived from behavior). Here we use implicit judgments derived from UBI selection behavior, scored using the Clicks Over Expected Clicks (COEC) model. The COEC model helps correct position bias by comparing each document’s actual click rate against the expected rate for its rank position. Documents that outperform their position score as relevant. Those that users select because they ranked first score near average.
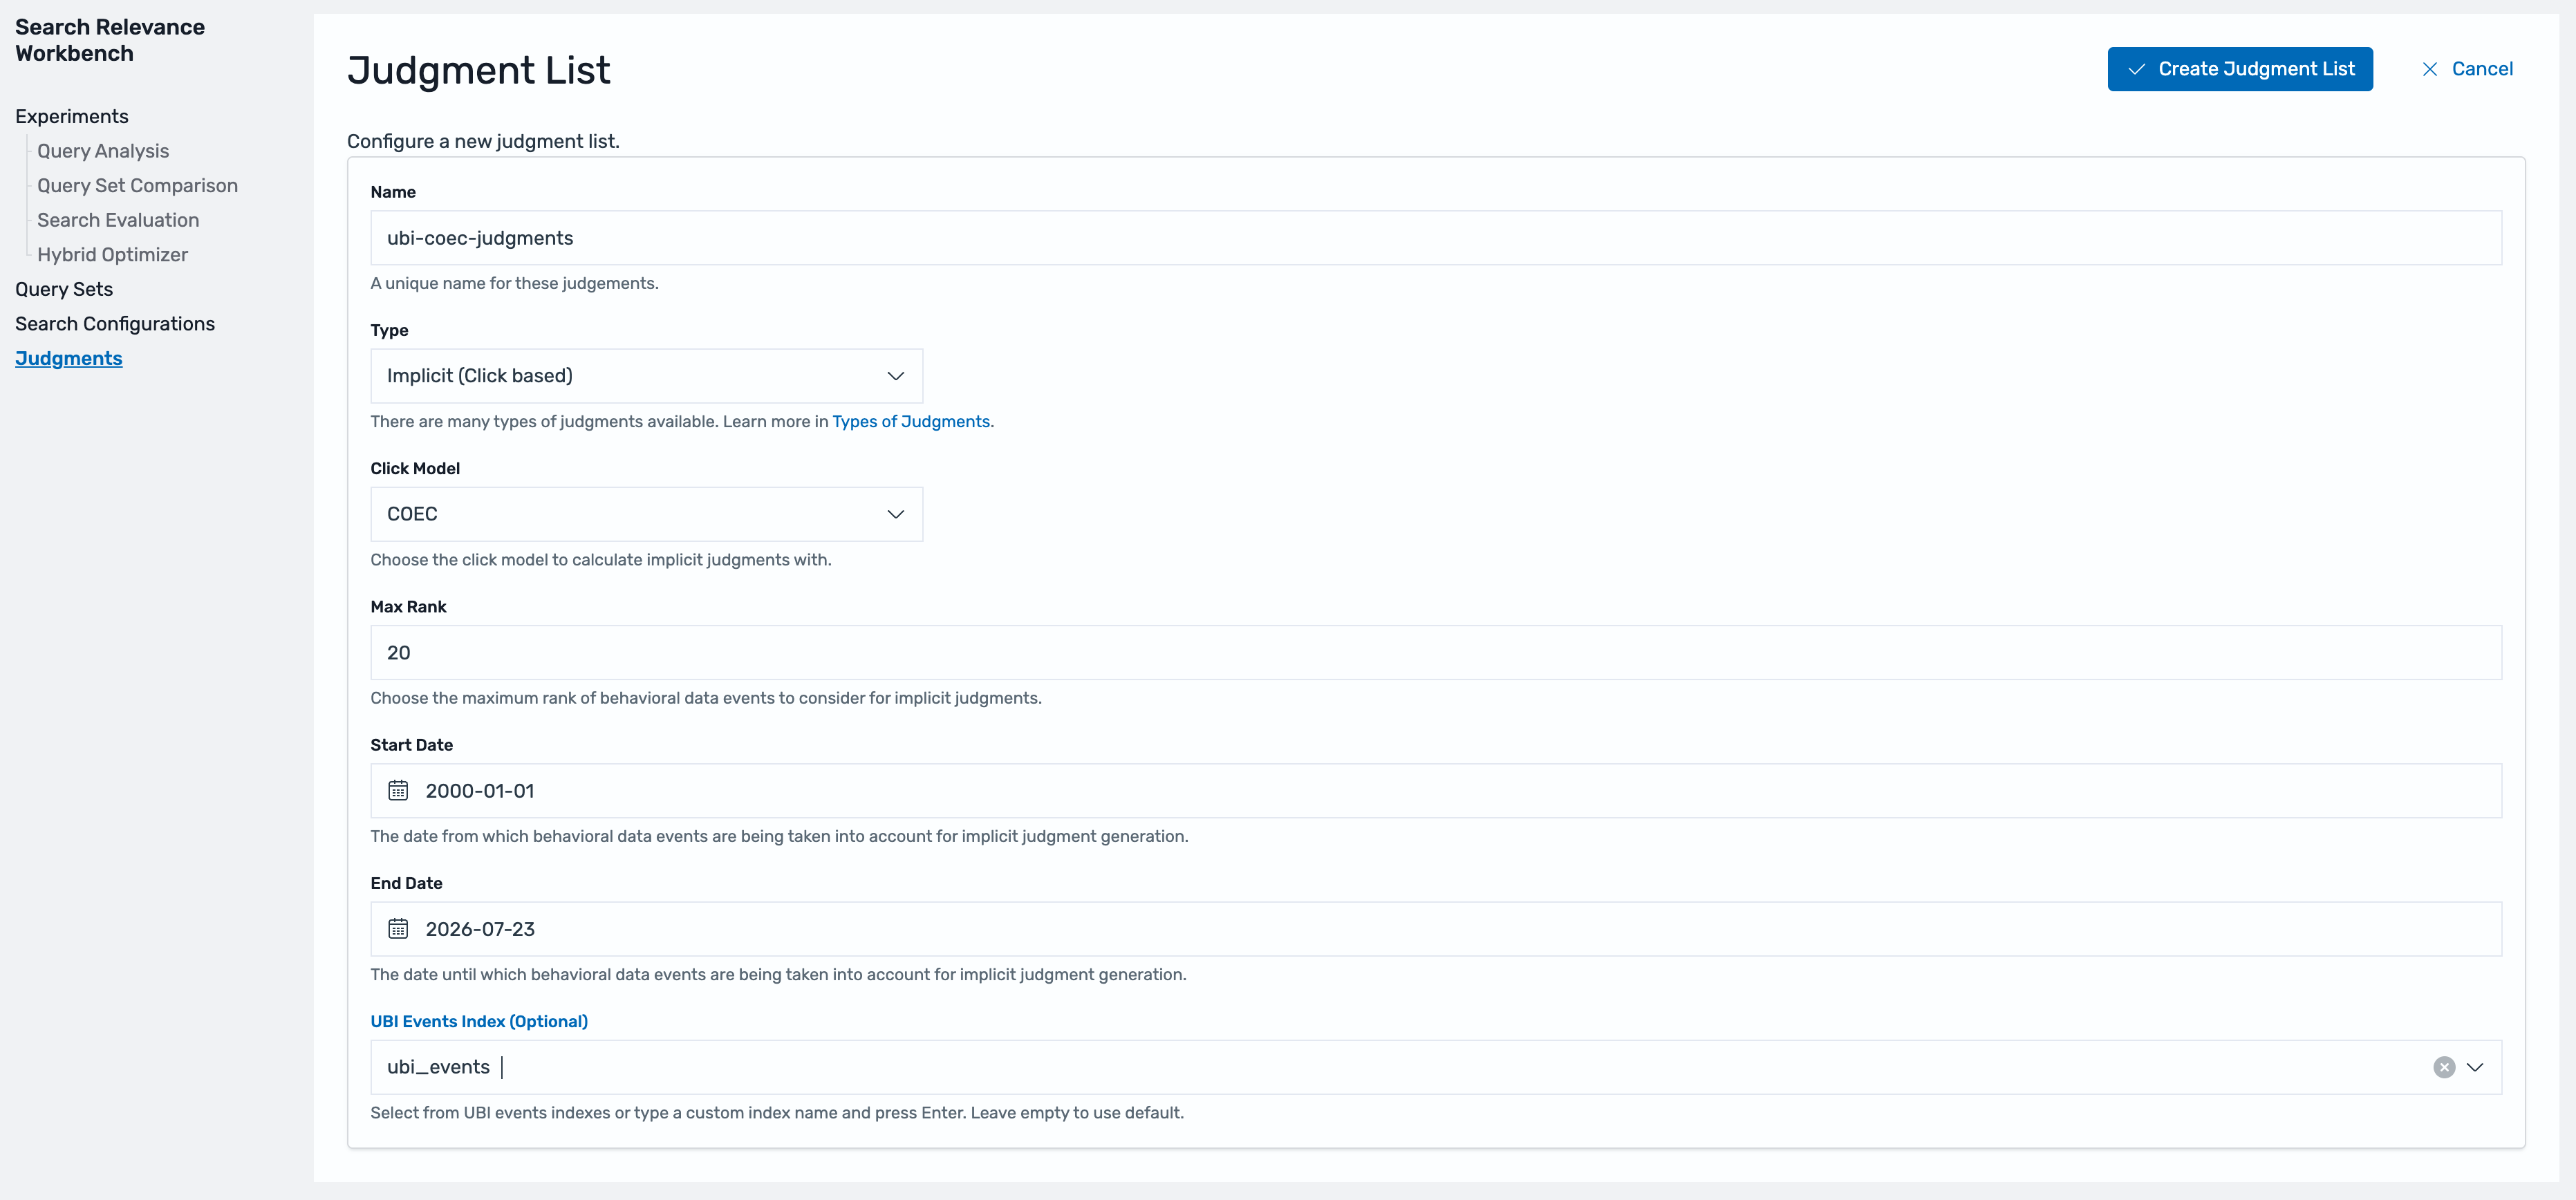
Judgment list creation screen with the Implicit click-based type and COEC click model selected

Figure 5: Creating an implicit judgment list with the Implicit (Click based) type and the COEC click model

Three things to get right before you run experiments:

  1. object_id in your events must match the document _id from your product catalog. The search configurations you define return this _id, which lets SRW join judgments to results.
  2. Implicit judgments are statistical. They need volume and query coverage. As a working rule of thumb, aim for hundreds to thousands of real sessions per query to separate signal from noise.
  3. Max Rank controls how deep in the result list events count. If users paginate, set it beyond a single page. We use 20 here.

Step 4: Run experiments

This post uses three SRW capabilities: Query Analysis, Query Set Comparison, and Search Evaluation. Query Analysis is a quick eyeball check: compare two configurations side by side for a specific query to see exactly what changed and why the metrics moved. The other two answer harder questions with numbers: how good a configuration is, and how two configurations compare against real relevance signals.

Query Set Comparison (also called pairwise comparison) takes two configurations and computes ranking similarity. Jaccard overlap measures how much the two result lists share, while Rank-Biased Overlap (RBO) weights agreement at the top of the list more heavily. Near-identical scores mean the change will barely register with users. Low overlap means a real ranking shift worth reviewing carefully before shipping. In this run, the two configurations score 0.93 Jaccard and 0.92 RBO, a modest but real shift. SRW cannot score zero-result queries like “handbag”: They show zero similarity in a comparison and Failed in an evaluation, a signal they need a different fix than ranking adjustments.
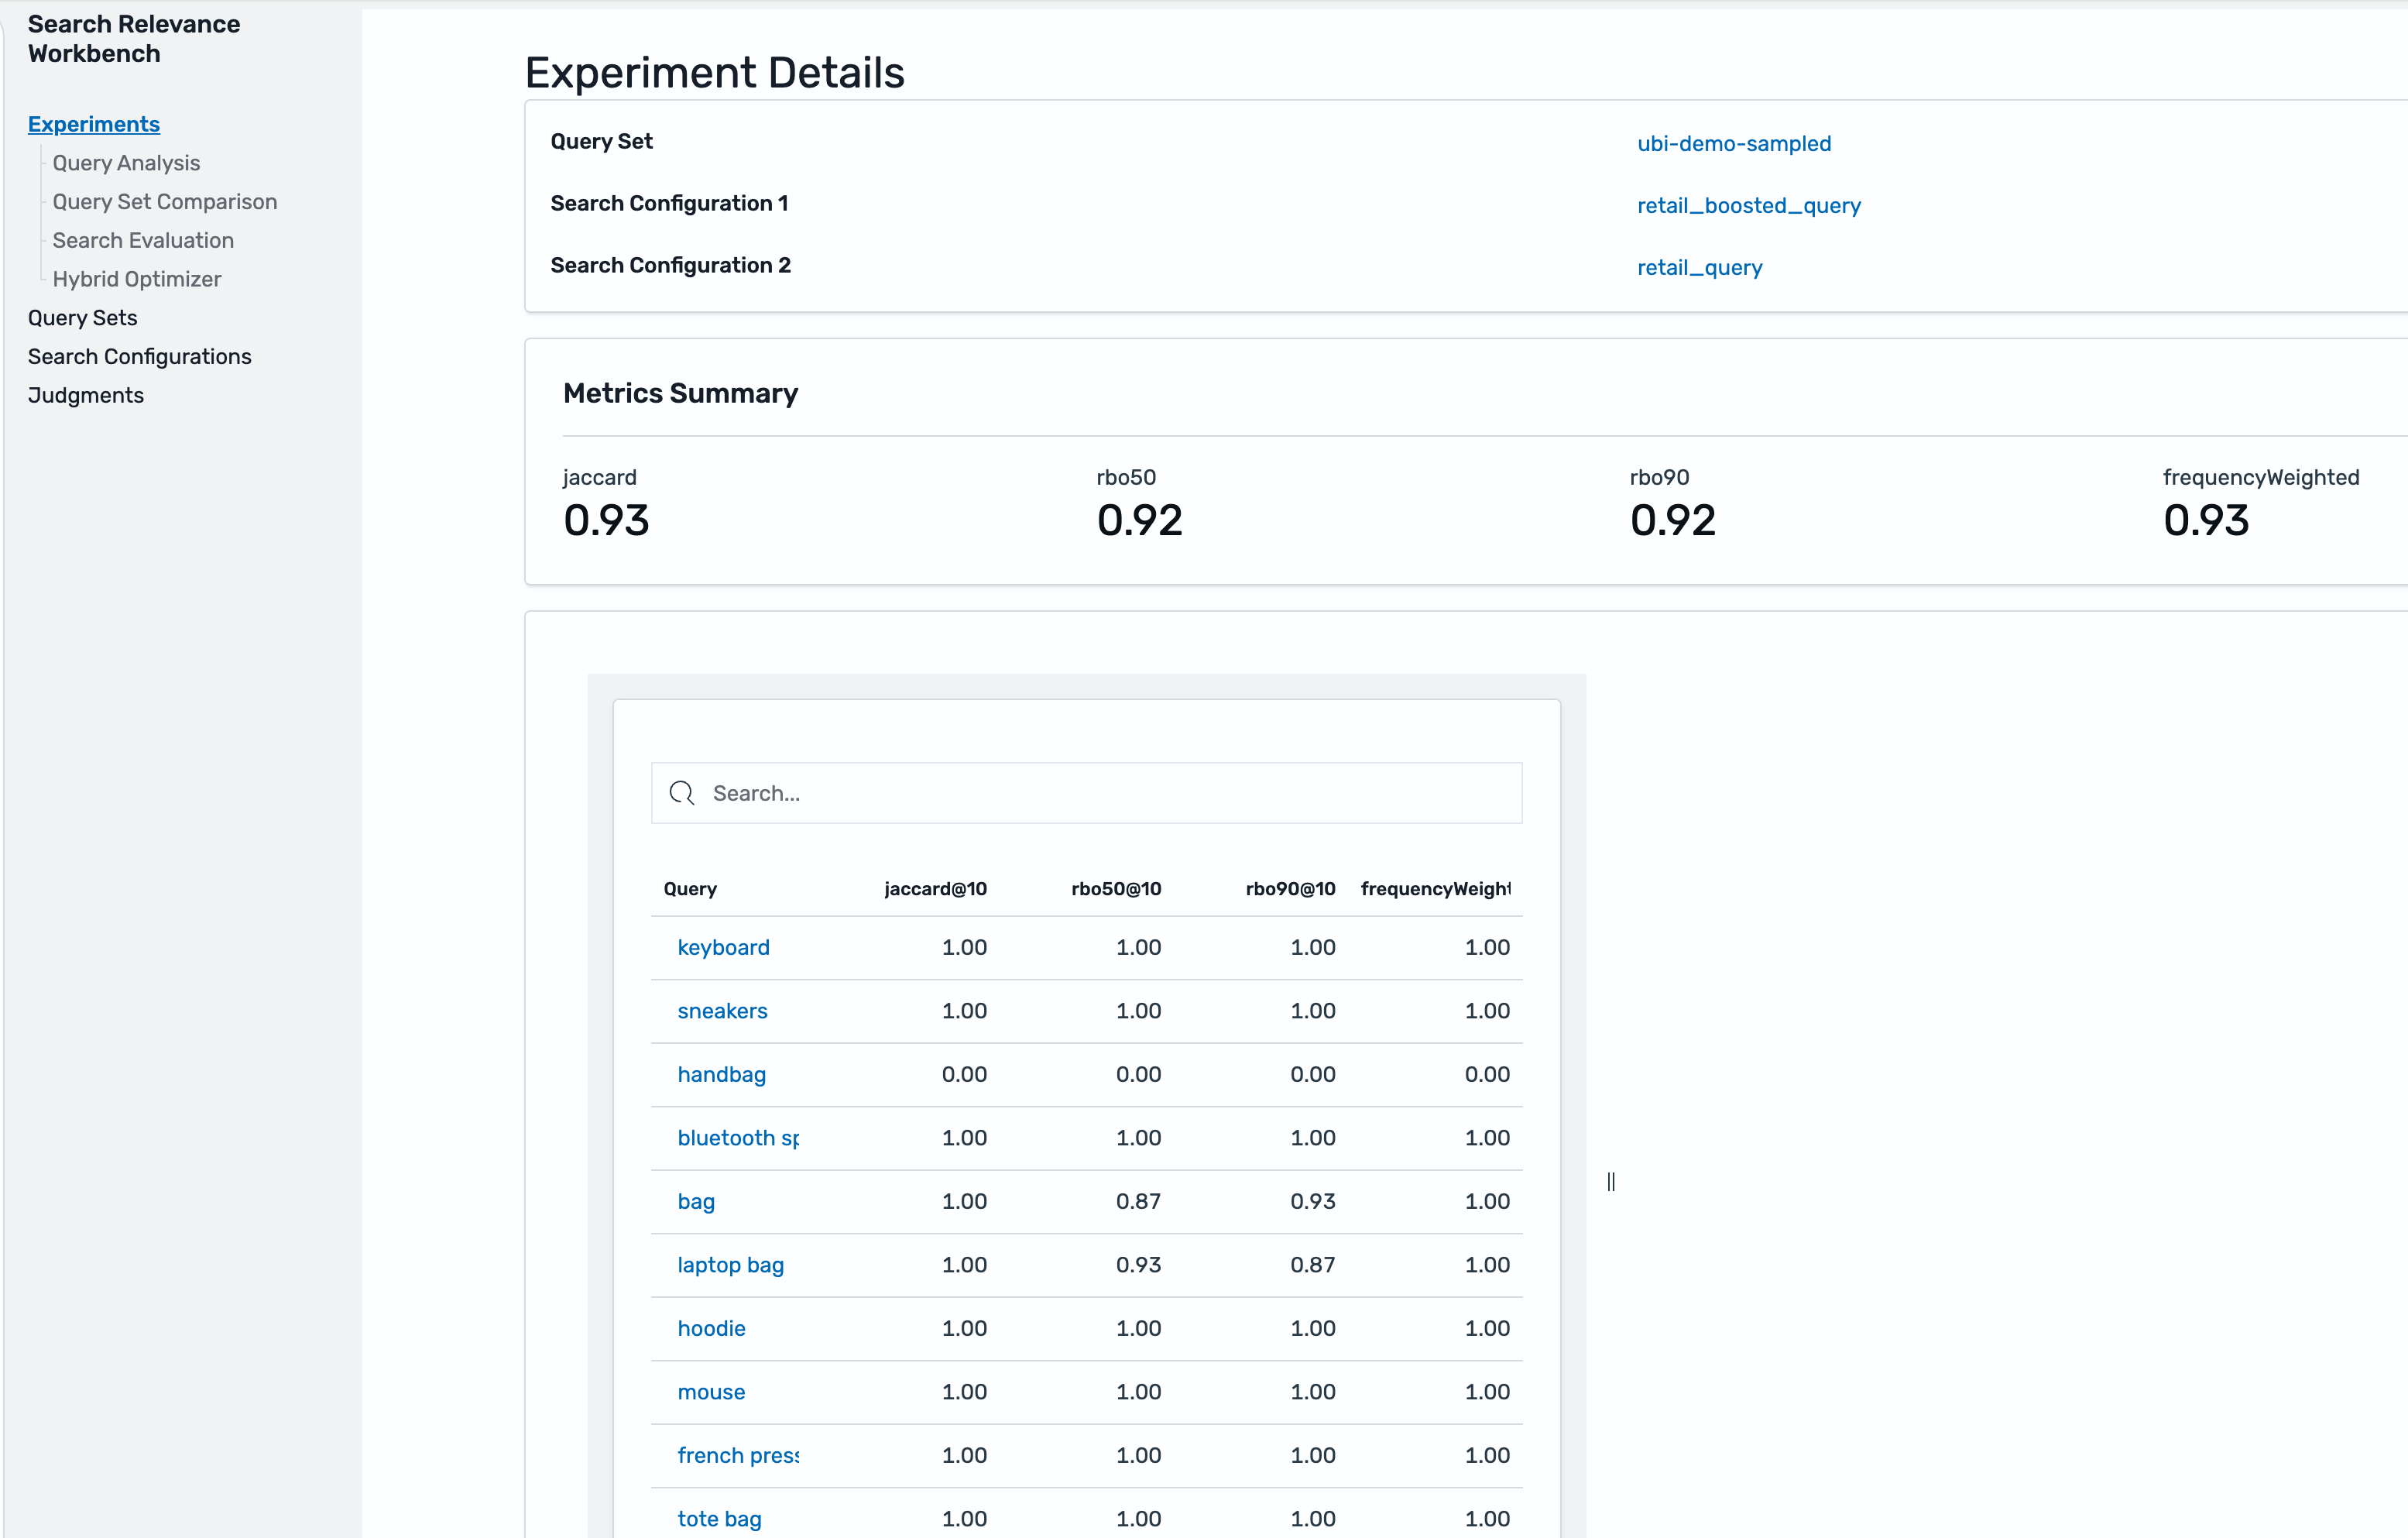
Query Set Comparison results showing Jaccard and Rank-Biased Overlap scores for the two configurations

Figure 6: Query Set Comparison showing Jaccard and Rank-Biased Overlap between the two configurations

Search Evaluation (also called pointwise evaluation) scores one configuration against your query set and judgment list across four metrics, each computed over the top k results (k=10 by default):

Metric What it measures What it tells you
Coverage@k Proportion of returned documents that have judgments How much to trust the other three metrics. Low Coverage means many results were never judged
Precision@k Fraction of the top k results that are relevant How many irrelevant results appear on the first page
MAP@k (Mean Average Precision) Precision averaged across ranks, rewarding relevant documents placed early Whether relevant results appear early, even when Precision ties
NDCG@k (Normalized Discounted Cumulative Gain) Graded judgment values, discounted by position (rank 1 counts more than rank 9) Whether the best results appear first. The primary comparison metric

Each pointwise experiment evaluates one configuration. To compare candidates, run one experiment per configuration and compare the results. In this run, the baseline (retail_query) scores Coverage@10 of 1.0, Precision@10 of 1.0, MAP@10 of 0.95, and NDCG@10 of 0.93, with the zero-result “handbag” query showing as Failed in the per-query detail.
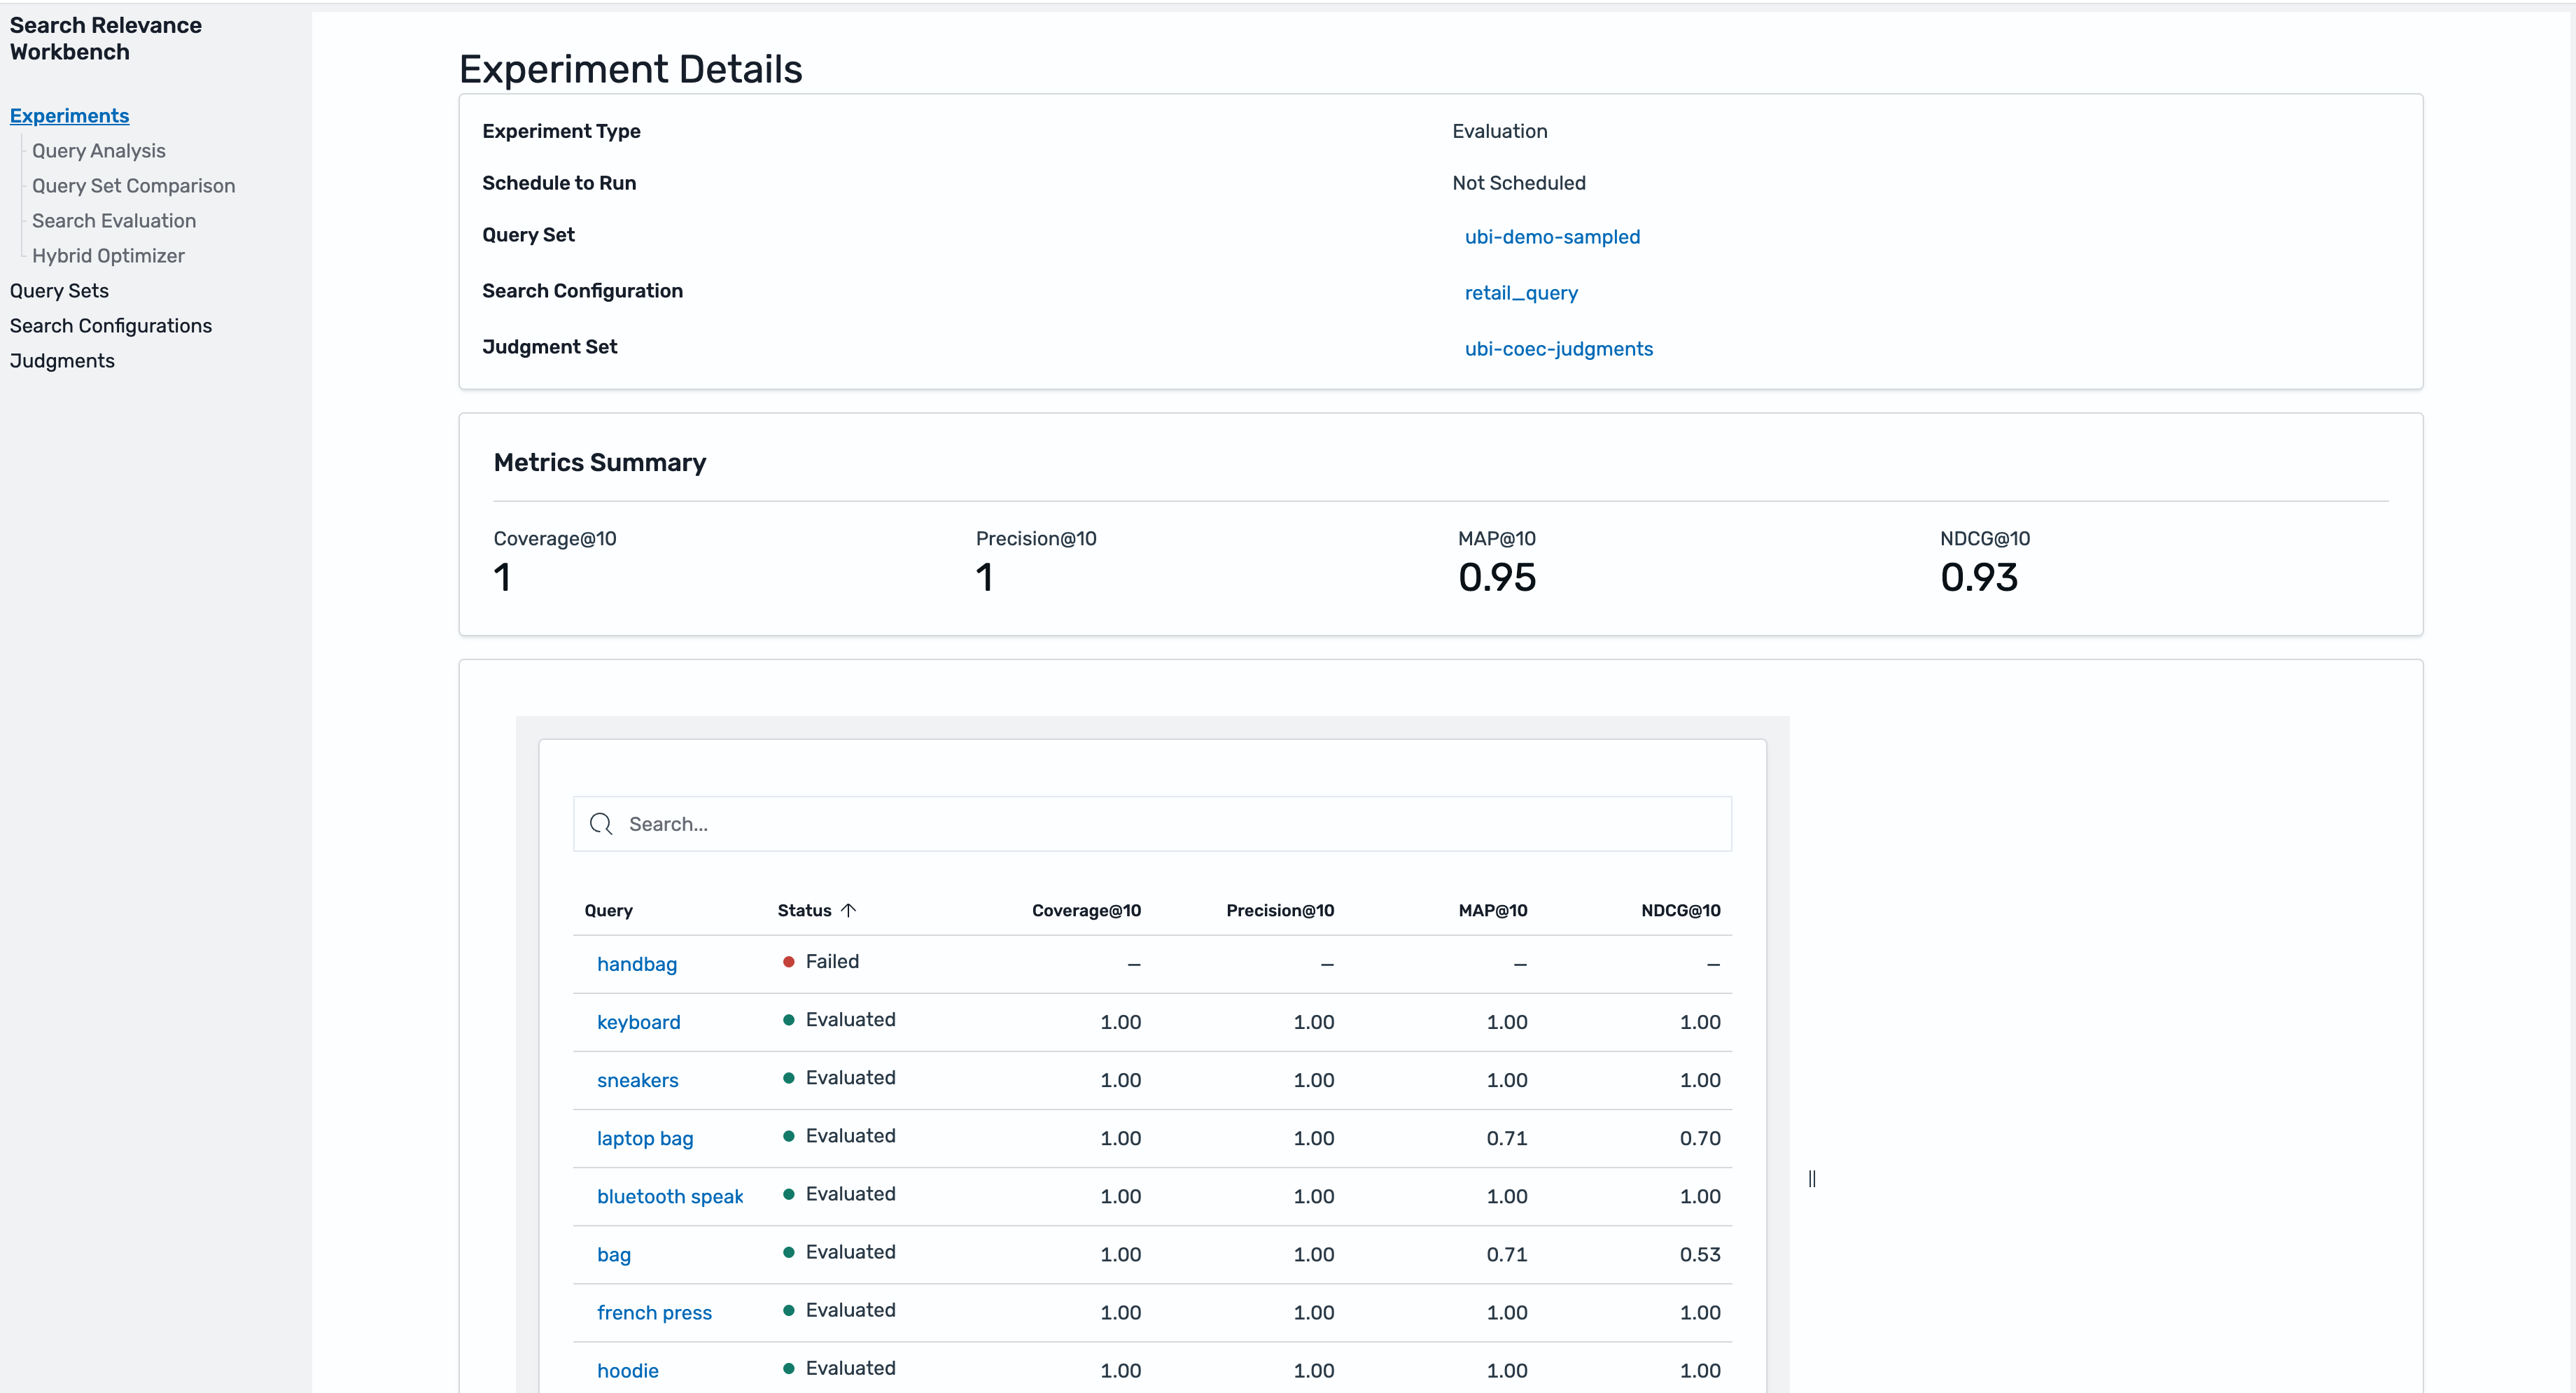
Search evaluation results showing Coverage, Precision, MAP, and NDCG at 10 with per-query detail

Figure 7: Search evaluation results for one configuration: Coverage, Precision, MAP, and NDCG at 10, with per-query detail

From measurement to improvement

The preceding experiments are the harness. The following are common levers to test with it. Express each as a new search configuration, evaluate it against the same query set and judgment list, and adopt it only if the metrics move:

  • Synonyms – One option for addressing known vocabulary gaps is to build synonyms. A search-time synonym token filter treats “handbag” and “bag” as equivalent, and with Amazon OpenSearch Service, you can hot deploy custom synonym packages without reindexing.
  • Field weights – Adjust the fields and boosts in a multi_match query, like the title^2 variant tested earlier.
  • Semantic retrieval – A hybrid query combines keyword and neural scores, addressing vocabulary mismatch as a class rather than term by term. Judgments evaluate it offline exactly like a lexical candidate.
  • Reranking – A rerank processor in a search pipeline reorders the top results using a cross-encoder model.

Clean up

To avoid future charges, delete the resources you created for this walkthrough:

  • Delete the two OpenSearch Ingestion pipelines. To reuse them later, stop them instead. A stopped pipeline keeps its configuration and incurs no OpenSearch Compute Unit (OCU) hour charges.
  • If you configured the optional Amazon S3 archive, delete the archived objects (or the bucket).
  • If you keep the domain, optionally delete the ubi_queries and ubi_events indices and the query sets, judgment lists, and experiments you created. These live on the domain and incur no separate charges.
  • If you created the domain specifically for this post, delete it to remove everything, including the resources in the previous step. Deleting a domain is irreversible. Don’t delete a domain that serves other workloads.

Conclusion

UBI collects the evidence, COEC turns it into judgments, and SRW experiments deliver the verdict: Coverage, Precision, MAP, and NDCG in place of guesswork. Ship the winning configuration, keep collecting, and the next round of judgments shows whether the improvement holds with real behavior. Where there used to be an opinion, there is now a number.

Everything here follows a repeatable pattern, and repeatable patterns lend themselves to automation. Part 2 walks through the Search Relevance Agent, available through the AI Assistant chat (the Ask AI button) in the OpenSearch UI. The agent analyzes your UBI signals, generates tuning hypotheses, and validates them offline before recommending changes. The pipeline you built in this post is the foundation. Stay tuned for Part 2.

To go deeper on the evaluation features, refer to the Search Relevance Workbench documentation.


About the authors

Aruna Govindaraju

Aruna Govindaraju

Aruna is an Amazon OpenSearch Specialist Solutions Architect and has worked with many commercial and open source search engines. She is passionate about search, relevancy, and user experience. Her expertise with correlating end-user signals with search engine behavior has helped many customers improve their search experience.

Sean Bjurstrom

Sean Bjurstrom

Sean is an Enterprise Support Lead in ISV accounts at Amazon Web Services, where he specializes in Analytics technologies and draws on his background in consulting to support customers on their analytics and cloud journeys. Sean is passionate about helping businesses harness the power of data to drive innovation and growth. Outside of work, he enjoys running and has participated in several marathons.

Utkarsh Agarwal

Utkarsh Agarwal

Utkarsh is a Cloud Support Engineer in the Support Engineering team at AWS. He provides guidance and technical assistance to customers, helping them build scalable, highly available, and secure solutions in the AWS Cloud. In his free time, he enjoys watching movies, TV series, and, of course, cricket! Lately, he has also been attempting to master foosball.

Cost Optimized Vector Database: Introduction to Amazon OpenSearch Service quantization techniques

Post Syndicated from Aruna Govindaraju original https://aws.amazon.com/blogs/big-data/cost-optimized-vector-database-introduction-to-amazon-opensearch-service-quantization-techniques/

The rise of generative AI applications has heightened the necessity to implement semantic search and natural language search. These advanced search features help find and retrieve conceptually relevant documents from enterprise content repositories to serve as prompts for generative AI models. Raw data within various source repositories in the form of text, images, audio, video, and so on are converted, with the help of embedding models, to a standard numerical representation called vectors that powers the semantic and natural language search. As organizations harness more sophisticated large language and foundational models to power their generative AI applications, supplemental embedding models are also evolving to handle large, high-dimension vector embedding. As the vector volume expands, there is a proportional increase in memory usage and computational requirements, resulting in higher operational costs. To mitigate this issue, various compression techniques can be used to optimize memory usage and computational efficiency.

Quantization is a lossy data compression technique aimed to lower computation and memory usage leading to lower costs, especially for high-volume data workloads. There are various techniques to compress data depending on the type and volume of the data. The usual technique is to map infinite values (or a relatively large list of finites) to smaller more discrete values. Vector compression can be achieved through two primary techniques: product quantization and scalar quantization. In the product quantization technique, the original vector dimension array is broken into multiple sub-vectors and each sub-vector is encoded into a fixed number of bits that represent the original vector. This method requires that you only store and search across the encoded sub-vector instead of the original vector. In scalar quantization, each dimension of the input vector is mapped from a 32-bit floating-point representation to a smaller data type.

Amazon OpenSearch Service, as a vector database, supports scalar and product quantization techniques to optimize memory usage and reduce operational costs.

OpenSearch as a vector database

OpenSearch is a distributed search and analytics service. The OpenSearch k-nearest neighbor (k-NN) plugin allows you to index, store, and search vectors. Vectors are stored in OpenSearch as a 32-bit float array of type knn_vector and that supports up to 16,000 dimensions per vector.

OpenSearch uses approximate nearest neighbor search to provide scalable vector search. The approximate k-NN algorithm retrieves results based on an estimation of the nearest vectors to a given query vector. Two main methods for performing approximate k-NN are the graph-based Hierarchical Navigable Small-World (HNSW) and the cluster-based Inverted File (IVF). These data structures are constructed and loaded into memory during the initial vector search operation. As vector volume grows, both the data structures and associated memory requirements for search operations scale proportionally.

For example, each HNSW graph with 32-bit float data takes approximately 1.1 * (4 * d + 8 * m) * num_vectors bytes of memory. Here, num_vectors represents the total quantity of vectors to be indexed, d is the number of dimensions determined by the embedding model you use to generate the vectors and m is the number of edges in the HSNW graphs, an index parameter that can be controlled to tune performance. Using this formula, memory requirements for vector storage for a configuration of 384 dimensions and an m value of 16 would be:

  • 1 million vectors: 1.830 GB (1.1 * (4 * 384 + 8 * 16) * 1000,000 bytes)
  • 1 billion vectors: 1830 GB (1.1 * (4 * 384 + 8 * 16) * 1,000,000,000 bytes)

Although approximate nearest neighbor search can be optimized to handle massive datasets with billions of vectors efficiently, the memory requirements for loading 32-bit full-precision vectors to memory during the search process can become prohibitively costly. To mitigate this, OpenSearch service supports the following four quantization techniques.

  • Binary quantization
  • Byte quantization
  • FP16 quantization
  • Product quantization

These techniques fall within the broader category of scalar and product quantization that we discussed earlier. In this post, you will learn quantization techniques for optimizing vector workloads on OpenSearch Service, focusing on memory reduction and cost-efficiency. It introduces the new disk-based vector search approach that enables efficient querying of vectors stored on disk without loading them into memory. The method integrates seamlessly with quantization techniques, featuring key configurations such as the on_disk mode and compression_level parameter. These settings facilitate built-in, out-of-the-box scalar quantization at the time of indexing.

Binary quantization (up to 32x compression)

Binary quantization (BQ) is a type of scalar quantization. OpenSearch leverages FAISS engine’s binary quantization, enabling up to 32x compression during indexing. This technique reduces the vector dimension from the default 32-bit float to a 1-bit binary by compressing the vectors into a 0s and 1s. OpenSearch supports indexing, storing and searching binary vectors. You can also choose to encode each vector dimension using 1, 2, or 4 bits, depending upon the desired compression factor as shown in the example below. The compression factor can be adjusted using bits settings. A value of 2 yields 16x compression, while 4 results in 8x compression. The default setting is 1. In binary quantization, the training is handled natively at the time of indexing, allowing you to avoid an additional preprocessing step.

To implement binary quantization, define the vector type as knn_vector and specify the encoder name as binary with the desired number of encoding bits. Note, the encoder parameter refers to a method used to compress vector data before storing it in the index. Optimize performance by using space_type, m, and ef_construction parameters. See the OpenSearch documentation for information about the underlying configuration of the approximate k-NN.

PUT my-vector-index
{
  "settings": {
    "index.knn": true
  },
  "mappings": {
    "properties": {
      "my_vector_field": {
        "type": "knn_vector",
        "dimension": 8,
        "method": {
          "name": "hnsw",
          "engine": "faiss",
          "space_type": "l2",
          "parameters": {
            "m": 16,
            "ef_construction": 512,
            "encoder": {
              "name": "binary",
              "parameters": {
                "bits": 1
              }
            }
          }
        }
      }
    }
  }
}

Memory requirements for implementing binary quantization with FAISS-HNSW:

1.1 * (bits * (d/8)+ 8 * m) * num_vectors bytes.

Compression Encoding bits

Memory required for 1 billion vector

with d=384 and m=16 (in GB)

32x 1 193.6
16x 2 246.4
8x 4 352.0

For detailed implementation steps on binary quantization, see the OpenSearch documentation.

Byte-quantization (4x compression)

Byte quantization compresses 32-bit floating-point dimensions to 8-bit integers, ranging from –128 to +127, reducing memory usage by 75%. OpenSearch supports indexing, storing, and searching byte vectors, which must be converted to 8-bit format prior to ingestion. To implement byte vectors, specify the k-NN vector field data_type as byte in the index mapping. This feature is compatible with both Lucene and FAISS engines. An example of creating an index for byte-quantized vectors follows.

PUT /my-vector-index
{
  "settings": {
    "index": {
      "knn": true,
      "knn.algo_param.ef_search": 100
    }
  },
  "mappings": {
    "properties": {
      "my_vector": {
        "type": "knn_vector",
        "dimension": 3,
        "data_type": "byte",
        "space_type": "l2",
        "method": {
          "name": "hnsw",
          "engine": "faiss",
          "parameters": {
            "ef_construction": 100,
            "m": 16
          }
        }
      }
    }
  }
}

This method requires ingesting a byte-quantized vector into OpenSearch for direct storage in the k-NN vector field (of byte type). However, the recently introduced disk-based vector search feature eliminates the need for external vector quantization. This feature will be discussed in detail later in this blog.

Memory requirements for implementing byte quantization with FAISS-HNSW:

1.1 * (1 * d + 8 * m) * num_vectors bytes.

For detailed implementation steps, see to the OpenSearch documentation. For performance metrics regarding accuracy, throughput, and latency, see Byte-quantized vectors in OpenSearch.

FAISS FP16 quantization (2x compression)

FP16 quantization is a technique that uses 16-bit floating-point scalar representation, reducing the memory usage by 50%. Each vector dimension is converted from 32-bit to 16-bit floating-point, effectively halving the memory requirements. The compressed vector dimensions must be in the range [–65504.0, 65504.0]. To implement FP16 quantization, create the index with the k-NN vector field and configure the following:

  • Set k-NN vector field method and engine to HNSW and FAISS, respectively.
  • Define encoder parameter and set name to sq and type to fp16.

Upon uploading 32-bit floating-point vectors to OpenSearch, the scalar quantization FP16 (SQfp16) automatically quantizes them to 16-bit floating-point vectors during ingestion and stores them in the vector field. The following example demonstrates the creation of the index for quantizing and storing FP16-quantized vectors.

PUT /my-vector-index
{
  "settings": {
    "index": {
      "knn": true,
      "knn.algo_param.ef_search": 100
    }
  },
  "mappings": {
    "properties": {
      "my_vector1": {
        "type": "knn_vector",
        "dimension": 3,
        "space_type": "l2",
        "method": {
          "name": "hnsw",
          "engine": "faiss",
          "parameters": {
            "encoder": {
              "name": "sq",
              "parameters": {
                "type": "fp16",
                "clip": true
              }
            },
            "ef_construction": 256,
            "m": 8
          }
        }
      }
    }
  }
}

Memory requirements for implementing FP16 quantization with FAISS-HNSW:

(1.1 * (2 * d + 8 * m) * num_vectors) bytes.

The preceding FP16 example introduces an optional Boolean parameter called clip, which defaults to false. When false, vectors with out-of-range values (values not between –65504.0 and +65504.0) are rejected. Setting clip to true enables rounding of out-of-range vector values to fit within the supported range. For detailed implementation steps, see the OpenSearch documentation. For performance metrics regarding accuracy, throughput, and latency, see Optimizing OpenSearch with Faiss FP16 scalar quantization: Enhancing memory efficiency and cost-effectiveness.

Product quantization

Product quantization (PQ) is an advanced dimension-reduction technique that offers significantly higher levels of compression. While conventional scalar quantization methods typically achieve up to 32x compression, PQ can provide compression levels of up to 64x, making it a more efficient solution for optimizing storage and cost. OpenSearch supports PQ with both IVF and HNSW method from FAISS engine. Product quantization partitions vectors into m sub-vectors, each encoded with a bit count determined by the code size. The resulting vector’s memory footprint is m * code_size bits.

FAISS product quantization involves three key steps:

  1. Create and populate a training index to build the PQ model, optimizing for accuracy.
  2. Execute the _train API on the training index to generate the quantizer model.
  3. Construct the vector index, configuring the kNN field to use the prepared quantizer model.

The following example demonstrates the three steps to setting up product quantization.

Step1: Create the training index. Populate the training index with an appropriate dataset, making sure of dimensional alignment with train-index specifications. Note that the training index requires a minimum of 256 documents.

PUT /train-index
{
  "settings": {
    "number_of_shards": 1,
    "number_of_replicas": 2
  },
  "mappings": {
    "properties": {
      "train-field": {
        "type": "knn_vector",
        "dimension": 4
      }
    }
  }
}

Step2: Create a quantizer model called my-model by running the _train API on the training index you just created. Note that the encoder with name defined as pq facilitates native vector quantization. Other parameters for encoder include code_size and m. FAISS-HNSW requires a code_size of 8 and a training dataset of at least 256 (2^code_size) documents. For detailed parameter specifications, see the PQ parameter reference.

POST /_plugins/_knn/models/my-model/_train
{
  "training_index": "train-index",
  "training_field": "train-field",
  "dimension": 4,
  "description": "My test model description",
  "method": {
    "name": "hnsw",
    "engine": "faiss",
    "parameters": {
      "encoder": {
        "name": "pq", 
         "parameters": {
           "code_size":8,
           "m":2
         }
      },
      "ef_construction": 256,
      "m": 8
    }
  }
}

Step3: Map the quantizer model to your vector index.

PUT /my-vector-index
{
  "settings": {
    "number_of_shards": 1,
    "number_of_replicas": 2,
    "index.knn": true
  },
  "mappings": {
    "properties": {
      "target-field": {
        "type": "knn_vector",
        "model_id": "my-model"
      }
    }
  }
}

Ingest the complete dataset into the newly created index, my-vector-index. The encoder will automatically process the incoming vectors, applying encoding and quantization based on the compression parameters (code_size and m) specified in the quantizer model configuration.

Memory requirements for implementing product quantization with FAISS-HNSW:

1.1*(((code_size / 8) * m + 24 + 8 * m) * num_vectors bytes. Here the code_size and m are parameters within the encoder parameter, num_vectors are the total number of vectors.

During quantization, each of the training vectors is broken down to multiple sub-vectors or sub-spaces, defined by a configurable value m. The number of bits to encode each of the sub-vector is controlled by parameter code_size. Each of the sub-vectors is then compressed or quantized separately by running the k-means clustering with the value k defined as 2^code_size. In this technique, the vector is compressed roughly by m * code_size bits.

For detailed implementation guidelines and understanding of the configurable parameters during product quantization, see the OpenSearch documentation. For performance metrics regarding accuracy, throughput and latency using FAISS IVF for PQ, see Choose the k-NN algorithm for your billion-scale use case with OpenSearch.

Disk-based vector search

Disk-based vector search optimizes query efficiency by using compressed vectors in memory while maintaining full-precision vectors on disk. This approach enables OpenSearch to perform searches across large vector datasets without the need to load entire vectors into memory, thus improving scalability and resource utilization. Implementation is achieved through two new configurations at index creation: mode and compression level. As of OpenSearch 2.17, the mode parameter can be set to either in_memory or on_disk during indexing. The previously discussed methods default to an in-memory mode. In this configuration, the vector index is constructed using either a graph (HNSW) or bucket (IVF) structure, which is then loaded into native memory during search operations. While offering excellent recall, this approach could impact memory usage, and scalability for high volume vector workload.

The on_disk mode optimizes vector search efficiency by storing full-precision vectors on disk while using real-time, native quantization during indexing. Coupled with adjustable compression levels, this approach allows only compressed vectors to be loaded into memory, thereby improving memory and resource utilization and search performance. The following compression levels correspond to various scalar quantization methods discussed earlier.

  • 32x: Binary quantization (1-bit dimensions)
  • 4x: Byte and integer quantization (8-bit dimensions)
  • 2x: FP16 quantization (16-bit dimensions)

This method also supports other compression levels such as 16x and 8x that aren’t available with the in-memory mode. To enable disk-based vector search, create the index with mode set to on_disk as shown in the following example.

PUT /my-vector-index
{
  "settings" : {
    "index": {
      "knn": true
    }
  },
  "mappings": {
    "properties": {
      "my_vector_field": {
        "type": "knn_vector",
        "dimension": 8,
        "space_type": "innerproduct",
        "data_type": "float",
        "mode": "on_disk"
      }
    }
  }
}

Configuring just the mode as on_disk employs the default configuration, which uses the FAISS engine and HNSW method with a 32x compression level (1-bit, binary quantization). The ef_construction to optimize index time latency defaults to 100. For more granular fine-tuning, you can override these k-NN parameters as shown in the example that follows.

PUT /my-vector-index
{
  "settings" : {
    "index": {
      "knn": true
    }
  },
  "mappings": {
    "properties": {
      "my_vector_field": {
        "type": "knn_vector",
        "dimension": 8,
        "space_type": "innerproduct",
        "data_type": "float",
        "mode": "on_disk",
        "compression_level": "16x",
        "method": {
          "name": "hnsw",
          "engine": "faiss",
          "parameters": {
            "ef_construction": 512
          }
        }
      }
    }
  }
}

Because quantization is a lossy compression technique, higher compression levels typically result in lower recall. To improve recall during quantization, you can configure the disk-based vector search to run in two phases using the search time configuration parameter ef_search and the oversample_factor as shown in the following example.

GET my-vector-index/_search
{
  "query": {
    "knn": {
      "my_vector_field": {
        "vector": [1.5, 2.5, 3.5, 4.5, 5.5, 6.5, 7.5, 8.5],
        "k": 5,
        "method_parameters": {
            "ef_search": 512
        },
        "rescore": {
            "oversample_factor": 10.0
        }
      }
    }
  }
}

In the first phase, oversample_factor * k results are retrieved from the quantized vectors in memory and the scores are approximated. In the second phase, the full-precision vectors of those oversample_factor * k results are loaded into memory from disk, and scores are recomputed against the full-precision query vector. The results are then reduced to the top k.

The oversample_factor for rescoring is determined by the configured dimension and compression level at indexing. For dimensions below 1,000, the factor is fixed at 5. For dimensions exceeding 1,000, the default factor varies based on the compression level, as shown in the following table.

Compression level Default oversample_factor for rescoring
32x (default) 3
16x 2
8x 2
4x No default rescoring
2x No default rescoring

As previously discussed, the oversample_factor can be dynamically adjusted at search time. This value presents a critical trade-off between accuracy and search efficiency. While a higher factor improves accuracy, it proportionally increases memory usage and reduces search throughput. See the OpenSearch documentation to learn more about disk-based vector search and understand the right usage for oversample_factor.

Performance assessment of quantization methods: Reviewing memory, recall, and query latency.

The OpenSearch documentation on approximate k-NN search provides a starting point for implementing vector similarity search. Additionally, Choose the k-NN algorithm for your billion-scale use case with OpenSearch offers valuable insights into designing efficient vector workloads for handling billions of vectors in production environments. It introduces product quantization techniques as a potential solution to reduce memory requirements and associated costs by scaling down the memory footprint.

The following table illustrates the memory requirements for storing and searching through 1 billion vectors using various quantization techniques. The table compares the default memory consumption of full-precision vector using the HNSW method against memory consumed by quantized vectors. The model employed in this analysis is the sentence-transformers/all-MiniLM-L12-v2, which operates with 384 dimensions. The raw metadata is assumed to be not more than 100Gb.

Without quantization
(in GB)
Product quantization
(in GB)
Scalar quantization
(in GB)
FP16 vectors Byte vectors Binary vectors
m value 16 16 16 16 16
pq_m, code_size 16, 8
Native memory consumption (GB) 1830.4 184.8 985.6 563.2 193.6
Total storage =
100 GB+vector
1930.4 284.8 1085.6 663.2 293.6

Reviewing the preceding table reveals that for a dataset comprising 1 billion vectors, the HNSW graph with 32-bit full-precision vector requires approximately 1830 GB of memory. Compression techniques such as product quantization can reduce this to 184.8 GB, while scalar quantization offers varying levels of compression. The following table summarizes the correlation between compression techniques and their impact on key performance indicators including cost savings, recall rate, and query latency. This analysis builds upon our previous assessment of memory usage to aid in selecting compression technique that meets your requirement.

The table presents two key search metrics: search latency at the 90th percentile (p90) and recall at 100.

  • Search latency @p90 indicates that 90% of search queries will be completed within that specific latency time.
  • recall@100 – The fraction of the top 100 ground truth neighbors found in the 100 results returned.
  Without quantization
(in GB)
Product quantization
(in GB)
Scalar quantization
(in GB)
  FP16 quantization
[mode=in_memory]
Byte quantization
[mode=in_memory]
Binary quantization
[mode=on_disk]
Preconditions/Datasets Applicable to all datasets Recall depends on the nature of the training data Works for dimension value in
range [-65536 to 65535]
Works for dimension value in
range [-128 to 127]
Works well for larger dimensions >=768
Preprocessing required? No Yes,
preprocessing/training is required
No No No
Rescoring No No No No Yes
Recall @100 >= 0.99 >0.7 >=0.95 >=0.95 >=0.90
p90 query latency (ms) <50 ms <50 ms <50 ms <50 ms <200 ms
Cost
(baseline $X)
$X $0.1*X
(up to 90% savings)
$0.5*X
(up to 50% savings)
$0.25*X
(up to 75%)
$0.15*X
(up to 85% savings)
Sample cost for a billion vector $20,923.14 $2,092.31 $10,461.57 $5,230.79 $3,138.47

The sample cost estimate for billion vector is based on a configuration optimized for cost. Please note that actual savings may vary based on your specific workload requirements and chosen configuration parameters. Notably in the table, product quantization offers up to 90% cost reduction compared to the baseline HNSW graph-based vector search cost ($X). Scalar quantization similarly yields proportional cost savings, ranging from 50% to 85% relative to the compressed memory footprint. The choice of compression technique involves balancing cost-effectiveness, accuracy, and performance, as it impacts precision and latency.

Conclusion

By leveraging OpenSearch’s quantization techniques, organizations can make informed tradeoffs between cost efficiency, performance, and recall, empowering them to fine-tune their vector database operations for optimal results. These quantization techniques significantly reduce memory requirements, improve query efficiency and offer built-in encoders for seamless compression. Whether you’re dealing with large-scale text embeddings, image features, or any other high-dimensional data, OpenSearch’s quantization techniques offer efficient solutions for vector search requirements, enabling the development of cost-effective, scalable, and high-performance systems.

As you move forward with your vector database projects, we encourage you to:

  1. Explore OpenSearch’s compression techniques in-depth
  2. Evaluate applicability of the right technique to your specific use case
  3. Determine the appropriate compression levels based on your requirements for recall and search latency
  4. Measure and compare cost savings based on accuracy, throughput, and latency

Stay informed about the latest developments in this rapidly evolving field, and don’t hesitate to experiment with different quantization techniques to find the optimal balance between cost, performance, and accuracy for your applications.


About the Authors

Aruna Govindaraju is an Amazon OpenSearch Specialist Solutions Architect and has worked with many commercial and open-source search engines. She is passionate about search, relevancy, and user experience. Her expertise with correlating end-user signals with search engine behavior has helped many customers improve their search experience.

Vamshi Vijay Nakkirtha is a software engineering manager working on the OpenSearch Project and Amazon OpenSearch Service. His primary interests include distributed systems. He is an active contributor to various OpenSearch projects such as k-NN, Geospatial, and dashboard-maps.

Power neural search with AI/ML connectors in Amazon OpenSearch Service

Post Syndicated from Aruna Govindaraju original https://aws.amazon.com/blogs/big-data/power-neural-search-with-ai-ml-connectors-in-amazon-opensearch-service/

With the launch of the neural search feature for Amazon OpenSearch Service in OpenSearch 2.9, it’s now effortless to integrate with AI/ML models to power semantic search and other use cases. OpenSearch Service has supported both lexical and vector search since the introduction of its k-nearest neighbor (k-NN) feature in 2020; however, configuring semantic search required building a framework to integrate machine learning (ML) models to ingest and search. The neural search feature facilitates text-to-vector transformation during ingestion and search. When you use a neural query during search, the query is translated into a vector embedding and k-NN is used to return the nearest vector embeddings from the corpus.

To use neural search, you must set up an ML model. We recommend configuring AI/ML connectors to AWS AI and ML services (such as Amazon SageMaker or Amazon Bedrock) or third-party alternatives. Starting with version 2.9 on OpenSearch Service, AI/ML connectors integrate with neural search to simplify and operationalize the translation of your data corpus and queries to vector embeddings, thereby removing much of the complexity of vector hydration and search.

In this post, we demonstrate how to configure AI/ML connectors to external models through the OpenSearch Service console.

Solution Overview

Specifically, this post walks you through connecting to a model in SageMaker. Then we guide you through using the connector to configure semantic search on OpenSearch Service as an example of a use case that is supported through connection to an ML model. Amazon Bedrock and SageMaker integrations are currently supported on the OpenSearch Service console UI, and the list of UI-supported first- and third-party integrations will continue to grow.

For any models not supported through the UI, you can instead set them up using the available APIs and the ML blueprints. For more information, refer to Introduction to OpenSearch Models. You can find blueprints for each connector in the ML Commons GitHub repository.

Prerequisites

Before connecting the model via the OpenSearch Service console, create an OpenSearch Service domain. Map an AWS Identity and Access Management (IAM) role by the name LambdaInvokeOpenSearchMLCommonsRole as the backend role on the ml_full_access role using the Security plugin on OpenSearch Dashboards, as shown in the following video. The OpenSearch Service integrations workflow is pre-filled to use the LambdaInvokeOpenSearchMLCommonsRole IAM role by default to create the connector between the OpenSearch Service domain and the model deployed on SageMaker. If you use a custom IAM role on the OpenSearch Service console integrations, make sure the custom role is mapped as the backend role with ml_full_access permissions prior to deploying the template.

Deploy the model using AWS CloudFormation

The following video demonstrates the steps to use the OpenSearch Service console to deploy a model within minutes on Amazon SageMaker and generate the model ID via the AI connectors. The first step is to choose Integrations in the navigation pane on the OpenSearch Service AWS console, which routes to a list of available integrations. The integration is set up through a UI, which will prompt you for the necessary inputs.

To set up the integration, you only need to provide the OpenSearch Service domain endpoint and provide a model name to uniquely identify the model connection. By default, the template deploys the Hugging Face sentence-transformers model, djl://ai.djl.huggingface.pytorch/sentence-transformers/all-MiniLM-L6-v2.

When you choose Create Stack, you are routed to the AWS CloudFormation console. The CloudFormation template deploys the architecture detailed in the following diagram.

The CloudFormation stack creates an AWS Lambda application that deploys a model from Amazon Simple Storage Service (Amazon S3), creates the connector, and generates the model ID in the output. You can then use this model ID to create a semantic index.

If the default all-MiniLM-L6-v2 model doesn’t serve your purpose, you can deploy any text embedding model of your choice on the chosen model host (SageMaker or Amazon Bedrock) by providing your model artifacts as an accessible S3 object. Alternatively, you can select one of the following pre-trained language models and deploy it to SageMaker. For instructions to set up your endpoint and models, refer to Available Amazon SageMaker Images.

SageMaker is a fully managed service that brings together a broad set of tools to enable high-performance, low-cost ML for any use case, delivering key benefits such as model monitoring, serverless hosting, and workflow automation for continuous training and deployment. SageMaker allows you to host and manage the lifecycle of text embedding models, and use them to power semantic search queries in OpenSearch Service. When connected, SageMaker hosts your models and OpenSearch Service is used to query based on inference results from SageMaker.

View the deployed model through OpenSearch Dashboards

To verify the CloudFormation template successfully deployed the model on the OpenSearch Service domain and get the model ID, you can use the ML Commons REST GET API through OpenSearch Dashboards Dev Tools.

The GET _plugins REST API now provides additional APIs to also view the model status. The following command allows you to see the status of a remote model:

GET _plugins/_ml/models/<modelid>

As shown in the following screenshot, a DEPLOYED status in the response indicates the model is successfully deployed on the OpenSearch Service cluster.

Alternatively, you can view the model deployed on your OpenSearch Service domain using the Machine Learning page of OpenSearch Dashboards.

This page lists the model information and the statuses of all the models deployed.

Create the neural pipeline using the model ID

When the status of the model shows as either DEPLOYED in Dev Tools or green and Responding in OpenSearch Dashboards, you can use the model ID to build your neural ingest pipeline. The following ingest pipeline is run in your domain’s OpenSearch Dashboards Dev Tools. Make sure you replace the model ID with the unique ID generated for the model deployed on your domain.

PUT _ingest/pipeline/neural-pipeline
{
  "description": "Semantic Search for retail product catalog ",
  "processors" : [
    {
      "text_embedding": {
        "model_id": "sfG4zosBIsICJFsINo3X",
        "field_map": {
           "description": "desc_v",
           "name": "name_v"
        }
      }
    }
  ]
}

Create the semantic search index using the neural pipeline as the default pipeline

You can now define your index mapping with the default pipeline configured to use the new neural pipeline you created in the previous step. Ensure the vector fields are declared as knn_vector and the dimensions are appropriate to the model that is deployed on SageMaker. If you have retained the default configuration to deploy the all-MiniLM-L6-v2 model on SageMaker, keep the following settings as is and run the command in Dev Tools.

PUT semantic_demostore
{
  "settings": {
    "index.knn": true,  
    "default_pipeline": "neural-pipeline",
    "number_of_shards": 1,
    "number_of_replicas": 1
  },
  "mappings": {
    "properties": {
      "desc_v": {
        "type": "knn_vector",
        "dimension": 384,
        "method": {
          "name": "hnsw",
          "engine": "nmslib",
          "space_type": "cosinesimil"
        }
      },
      "name_v": {
        "type": "knn_vector",
        "dimension": 384,
        "method": {
          "name": "hnsw",
          "engine": "nmslib",
          "space_type": "cosinesimil"
        }
      },
      "description": {
        "type": "text" 
      },
      "name": {
        "type": "text" 
      } 
    }
  }
}

Ingest sample documents to generate vectors

For this demo, you can ingest the sample retail demostore product catalog to the new semantic_demostore index. Replace the user name, password, and domain endpoint with your domain information and ingest raw data into OpenSearch Service:

curl -XPOST -u 'username:password' 'https://domain-end-point/_bulk' --data-binary @semantic_demostore.json -H 'Content-Type: application/json'

Validate the new semantic_demostore index

Now that you have ingested your dataset to the OpenSearch Service domain, validate if the required vectors are generated using a simple search to fetch all fields. Validate if the fields defined as knn_vectors have the required vectors.

Compare lexical search and semantic search powered by neural search using the Compare Search Results tool

The Compare Search Results tool on OpenSearch Dashboards is available for production workloads. You can navigate to the Compare search results page and compare query results between lexical search and neural search configured to use the model ID generated earlier.

Clean up

You can delete the resources you created following the instructions in this post by deleting the CloudFormation stack. This will delete the Lambda resources and the S3 bucket that contain the model that was deployed to SageMaker. Complete the following steps:

  1. On the AWS CloudFormation console, navigate to your stack details page.
  2. Choose Delete.

  1. Choose Delete to confirm.

You can monitor the stack deletion progress on the AWS CloudFormation console.

Note that, deleting the CloudFormation stack doesn’t delete the model deployed on the SageMaker domain and the AI/ML connector created. This is because these models and the connector can be associated with multiple indexes within the domain. To specifically delete a model and its associated connector, use the model APIs as shown in the following screenshots.

First, undeploy the model from the OpenSearch Service domain memory:

POST /_plugins/_ml/models/<model_id>/_undeploy

Then you can delete the model from the model index:

DELETE /_plugins/_ml/models/<model_id>

Lastly, delete the connector from the connector index:

DELETE /_plugins/_ml/connectors/<connector_id>

Conclusion

In this post, you learned how to deploy a model in SageMaker, create the AI/ML connector using the OpenSearch Service console, and build the neural search index. The ability to configure AI/ML connectors in OpenSearch Service simplifies the vector hydration process by making the integrations to external models native. You can create a neural search index in minutes using the neural ingestion pipeline and the neural search that use the model ID to generate the vector embedding on the fly during ingest and search.

To learn more about these AI/ML connectors, refer to Amazon OpenSearch Service AI connectors for AWS services, AWS CloudFormation template integrations for semantic search, and Creating connectors for third-party ML platforms.


About the Authors

Aruna Govindaraju is an Amazon OpenSearch Specialist Solutions Architect and has worked with many commercial and open source search engines. She is passionate about search, relevancy, and user experience. Her expertise with correlating end-user signals with search engine behavior has helped many customers improve their search experience.

Dagney Braun is a Principal Product Manager at AWS focused on OpenSearch.
Perform accent-insensitive search using OpenSearch

Post Syndicated from Aruna Govindaraju original https://aws.amazon.com/blogs/big-data/perform-accent-insensitive-search-using-opensearch/

We often need our text search to be agnostic of accent marks. Accent-insensitive search, also called diacritics-agnostic search, is where search results are the same for queries that may or may not contain Latin characters such as à, è, Ê, ñ, and ç. Diacritics are English letters with an accent to mark a difference in pronunciation. In recent years, words with diacritics have trickled into the mainstream English language, such as café or protégé. Well, touché! OpenSearch has the answer!

OpenSearch is a scalable, flexible, and extensible open-source software suite for your search workload. OpenSearch can be deployed in three different modes: the self-managed open-source OpenSearch, the managed Amazon OpenSearch Service, and Amazon OpenSearch Serverless. All three deployment modes are powered by Apache Lucene, and offer text analytics using the Lucene analyzers.

In this post, we demonstrate how to perform accent-insensitive search using OpenSearch to handle diacritics.

Solution overview

Lucene Analyzers are Java libraries that are used to analyze text while indexing and searching documents. These analyzers consist of tokenizers and filters. The tokenizers split the incoming text into one or more tokens, and the filters are used to transform the tokens by modifying or removing the unnecessary characters.

OpenSearch supports custom analyzers, which enable you to configure different combinations of tokenizers and filters. It can consist of character filters, tokenizers, and token filters. In order to enable our diacritic-insensitive search, we configure custom analyzers that use the ASCII folding token filter.

ASCIIFolding is a method used to covert alphabetic, numeric, and symbolic Unicode characters that aren’t in the first 127 ASCII characters (the Basic Latin Unicode block) into their ASCII equivalents, if one exists. For example, the filter changes “à” to “a”. This allows search engines to return results agnostic of the accent.

In this post, we configure accent-insensitive search using the ASCIIFolding filter supported in OpenSearch Service. We ingest a set of European movie names with diacritics and verify search results with and without the diacritics.

Create an index with a custom analyzer

We first create the index asciifold_movies with custom analyzer custom_asciifolding:

PUT /asciifold_movies
{
  "settings": {
    "analysis": {
      "analyzer": {
        "custom_asciifolding": {
          "tokenizer": "standard",
          "filter": [
            "my_ascii_folding"
          ]
        }
      },
      "filter": {
        "my_ascii_folding": {
          "type": "asciifolding",
          "preserve_original": true
        }
      }
    }
  },
  "mappings": {
    "properties": {
      "title": {
        "type": "text",
        "analyzer": "custom_asciifolding",
        "fields": {
          "keyword": {
            "type": "keyword",
            "ignore_above": 256
          }
        }
      }
    }
  }
}

Ingest sample data

Next, we ingest sample data with Latin characters into the index asciifold_movies:

POST _bulk
{ "index" : { "_index" : "asciifold_movies", "_id":"1"} }
{  "title" : "Jour de fête"}
{ "index" : { "_index" : "asciifold_movies", "_id":"2"} }
{  "title" : "La gloire de mon père" }
{ "index" : { "_index" : "asciifold_movies", "_id":"3"} }
{  "title" : "Le roi et l’oiseau" }
{ "index" : { "_index" : "asciifold_movies", "_id":"4"} }
{  "title" : "Être et avoir" }
{ "index" : { "_index" : "asciifold_movies", "_id":"5"} }
{  "title" : "Kirikou et la sorcière"}
{ "index" : { "_index" : "asciifold_movies", "_id":"6"} }
{  "title" : "Señora Acero"}
{ "index" : { "_index" : "asciifold_movies", "_id":"7"} }
{  "title" : "Señora garçon"}
{ "index" : { "_index" : "asciifold_movies", "_id":"8"} }
{  "title" : "Jour de fete"}

Query the index

Now we query the asciifold_movies index for words with and without Latin characters.

Our first query uses an accented character:

GET asciifold_movies/_search
{
  "query": {
    "match": {
      "title": "fête"
    }
  }
}

Our second query uses a spelling of the same word without the accent mark:

GET asciifold_movies/_search
{
  "query": {
    "match": {
      "title": "fete"
    }
  }
}

In the preceding queries, the search terms “fête” and “fete” return the same results:

{
  "took": 10,
  "timed_out": false,
  "_shards": {
    "total": 5,
    "successful": 5,
    "skipped": 0,
    "failed": 0
  },
  "hits": {
    "total": {
      "value": 2,
      "relation": "eq"
    },
    "max_score": 0.7361701,
    "hits": [
      {
        "_index": "asciifold_movies",
        "_id": "8",
        "_score": 0.7361701,
        "_source": {
          "title": "Jour de fete"
        }
      },
      {
        "_index": "asciifold_movies",
        "_id": "1",
        "_score": 0.42547938,
        "_source": {
          "title": "Jour de fête"
        }
      }
    ]
  }
}

Similarly, try comparing results for “señora” and “senora” or “sorcière” and “sorciere.” The accent-insensitive results are due to the ASCIIFolding filter used with the custom analyzers.

Enable aggregations for fields with accents

Now that we have enabled accent-insensitive search, let’s look at how we can make aggregations work with accents.

Try the following query on the index:

GET asciifold_movies/_search
{
  "size": 0,
  "aggs": {
    "test": {
      "terms": {
        "field": "title.keyword"
      }
    }
  }
}

We get the following response:

"aggregations" : {
    "test" : {
      "doc_count_error_upper_bound" : 0,
      "sum_other_doc_count" : 0,
      "buckets" : [
        {
          "key" : "Jour de fete",
          "doc_count" : 1
        },
        {
          "key" : "Jour de fête",
          "doc_count" : 1
        },
        {
          "key" : "Kirikou et la sorcière",
          "doc_count" : 1
        },
        {
          "key" : "La gloire de mon père",
          "doc_count" : 1
        },
        {
          "key" : "Le roi et l’oiseau",
          "doc_count" : 1
        },
        {
          "key" : "Señora Acero",
          "doc_count" : 1
        },
        {
          "key" : "Señora garçon",
          "doc_count" : 1
        },
        {
          "key" : "Être et avoir",
          "doc_count" : 1
        }
      ]
    }
  }

Create accent-insensitive aggregations using a normalizer

In the previous example, the aggregation returns two different buckets, one for “Jour de fête” and one for “Jour de fete.” We can enable aggregations to create one bucket for the field, regardless of the diacritics. This is achieved using the normalizer filter.

The normalizer supports a subset of character and token filters. Using just the defaults, the normalizer filter is a simple way to standardize Unicode text in a language-independent way for search, thereby standardizing different forms of the same character in Unicode and allowing diacritic-agnostic aggregations.

Let’s modify the index mapping to include the normalizer. Delete the previous index, then create a new index with the following mapping and ingest the same dataset:

PUT /asciifold_movies
{
  "settings": {
    "analysis": {
      "analyzer": {
        "custom_asciifolding": {
          "tokenizer": "standard",
          "filter": [
            "my_ascii_folding"
          ]
        }
      },
      "filter": {
        "my_ascii_folding": {
          "type": "asciifolding",
          "preserve_original": true
        }
      },
      "normalizer": {
        "custom_normalizer": {
          "type": "custom",
          "filter": "asciifolding"
        }
      }
    }
  },
  "mappings": {
    "properties": {
      "title": {
        "type": "text",
        "analyzer": "custom_asciifolding",
        "fields": {
          "keyword": {
            "type": "keyword",
            "ignore_above": 256,
            "normalizer": "custom_normalizer"
          }
        }
      }
    }
  }
}

After you ingest the same dataset, try the following query:

GET asciifold_movies/_search
{
  "size": 0,
  "aggs": {
    "test": {
      "terms": {
        "field": "title.keyword"
      }
    }
  }
}

We get the following results:

"aggregations" : {
    "test" : {
      "doc_count_error_upper_bound" : 0,
      "sum_other_doc_count" : 0,
      "buckets" : [
        {
          "key" : "Jour de fete",
          "doc_count" : 2
        },
        {
          "key" : "Etre et avoir",
          "doc_count" : 1
        },
        {
          "key" : "Kirikou et la sorciere",
          "doc_count" : 1
        },
        {
          "key" : "La gloire de mon pere",
          "doc_count" : 1
        },
        {
          "key" : "Le roi et l'oiseau",
          "doc_count" : 1
        },
        {
          "key" : "Senora Acero",
          "doc_count" : 1
        },
        {
          "key" : "Senora garcon",
          "doc_count" : 1
        }
      ]
    }
  }

Now we compare the results, and we can see the aggregations with term “Jour de fête” and “Jour de fete” are rolled up into one bucket with doc_count=2.

Summary

In this post, we showed how to enable accent-insensitive search and aggregations by designing the index mapping to do ASCII folding for search tokens and normalize the keyword field for aggregations. You can use the OpenSearch query DSL to implement a range of search features, providing a flexible foundation for structured and unstructured search applications. The Open Source OpenSearch community has also extended the product to enable support for natural language processing, machine learning algorithms, custom dictionaries, and a wide variety of other plugins.

If you have feedback about this post, submit it in the comments section. If you have questions about this post, start a new thread on the Amazon OpenSearch Service forum or contact AWS Support.


About the Author

Aruna Govindaraju is an Amazon OpenSearch Specialist Solutions Architect and has worked with many commercial and open-source search engines. She is passionate about search, relevancy, and user experience. Her expertise with correlating end-user signals with search engine behavior has helped many customers improve their search experience. Her favorite pastime is hiking the New England trails and mountains.