All posts by Omar Gonzalez

Publishing LMS courses with a Kiro SCORM pipeline

Post Syndicated from Omar Gonzalez original https://aws.amazon.com/blogs/architecture/publishing-lms-courses-with-a-kiro-scorm-pipeline/

Publishing a Shareable Content Object Reference Model (SCORM) course to a learning management system (LMS) is rarely as straightforward as writing the course. The LMS needs SCORM packages to adhere to a standard format for successful import and launch. Producing one by hand means restructuring slides into modules and hand-editing SCORM manifests. The packaging mechanics pull authors away from developing the course content itself.

This post shows how to use Kiro, an agentic AI with an integrated development environment (IDE) and a CLI, to automate the conversion of raw training material into compliant SCORM packages. Testing with a small course included in the sample produced a SCORM package in a few minutes.

Solution overview

Kiro structures course content and guides the author through the publishing workflow. Figure 1 shows the end-to-end pipeline from raw material to upload-ready package.
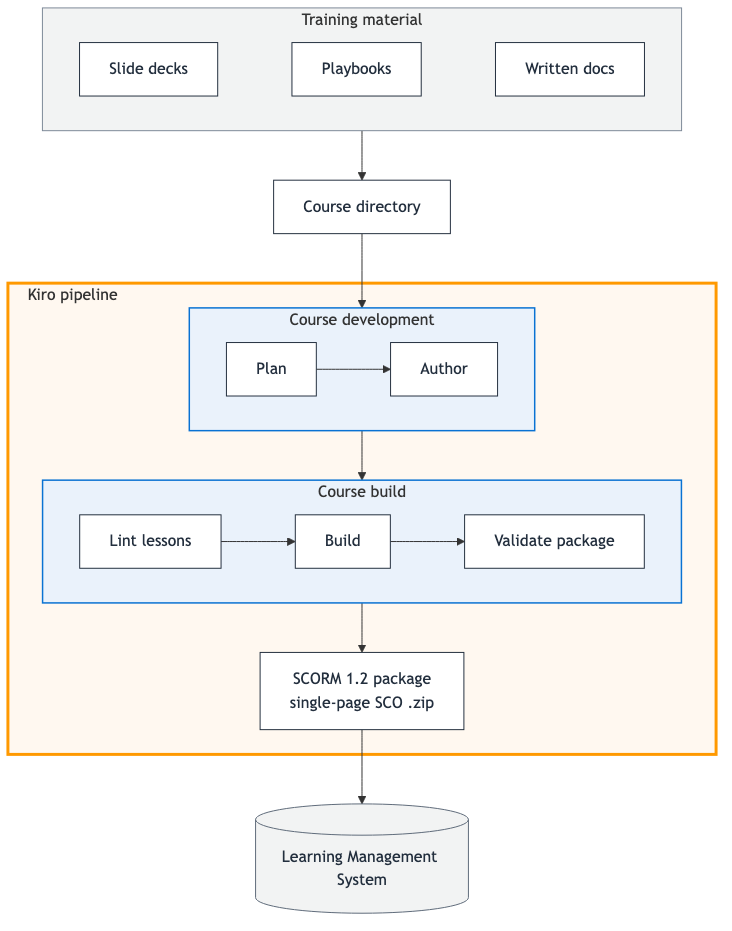
Diagram of the two-layer Kiro SCORM pipeline: source material flows into Kiro, which structures the content and runs the build to produce an upload-ready SCORM package for the LMS.

Figure 1: Kiro course publishing pipeline overview

An author places raw training material (slide decks, playbooks, and written docs) in a course folder, and Kiro runs two pipeline stages. Course Development includes planning and authoring lessons. Course Build includes linting the lessons, building the SCORM package, and validating the SCORM package. The output is a SCORM 1.2 .zip ready to upload to your LMS. You drive the whole pipeline from a Kiro conversation. Start by loading your material into a course folder, ask Kiro to build the course, and it hands back the upload-ready .zip file.

The Kiro building blocks this pipeline uses

Kiro is an agentic AI available as an IDE and a CLI (kiro-cli). This pipeline is built from three Kiro primitives:

  • Steering – Markdown files that give Kiro persistent context (.kiro/steering/) about your workspace. Steering loads automatically. always files load in every session, fileMatch files load when you touch files they govern, and manual files load on demand.
  • Specs – Specifications (.kiro/specs/) that formalize the development process for features or bug fixes.
  • Hooks – Automated triggers (.kiro/hooks/) that run prompts or shell commands when events occur in the IDE, such as creating a file, saving a file, or ending a session.

The LMS content publishing pipeline

The following sections walk through the steps a course goes through and the parts that carry them out.

How a course gets built

For a new course, Kiro works through six steps with you in conversation:

  1. Add source material to courses/<name>/ (slide decks, Word, PDFs, playbooks, Markdown docs).
  2. Plan – Kiro reads the source and creates the course.yaml manifest.
  3. Author – Kiro converts the source into a lesson.md per module.
  4. Lint – Check the authored lessons for structural problems such as missing frontmatter, broken image paths, or a knowledge check with no correct answer.
  5. Build – Render the lessons into one index.html and compress the SCORM package.
  6. Validate – Confirm the .zip file is a well-formed SCORM 1.2 package before it goes to the LMS.

The course manifest

Each course starts as a single manifest, course.yaml, that declares its modules, source material, and SCORM build configuration. Kiro creates the manifest at step 2, after you upload your source content and ask it to build a course.

course:
  title: "Build a SCORM Course from Markdown"
  short_name: "sample-course"
  short_description: "A three-module example course."
  default_language: en-US
  total_duration_minutes: 30

modules:
  - id: module-1
    title: "The Authoring Pipeline"
    target_duration_minutes: 10
  # ...

scorm:
  version: "1.2"
  output: scorm/dist/sample-course.zip
  passing_score: 100
  min_page_dwell_seconds: 5

A few notable settings you can customize:

  • min_page_dwell_seconds sets the minimum time a learner must spend on a page before the Next button unlocks.
  • target_duration_minutes sets each module’s expected completion time, shown to learners on the course home page.
  • total_duration_minutes sets the course-level expected completion time, shown to learners and reported to the LMS.
  • passing_score sets the score a learner must reach for the LMS to mark the course complete (written into the SCORM manifest as the mastery score).

Steering is where the pipeline’s knowledge lives

Steering is where this pipeline keeps everything Kiro needs to know. Steering files hold three kinds of knowledge:

  • Lessons learned – The SCORM knowledge accumulated from actually building and running courses.
  • Authoring conventions – How to break source material into modules and lessons, plus writing-style guidance so each lesson.md reads as polished, learner-facing content.
  • The repository contract – The uniform courses/<name>/ layout every course follows, so the same shared scripts work for every course.

Each steering file loads in one of the three modes from earlier: always, fileMatch, or manual. Every session picks up only the guidance it needs. The steering files in the sample repository are listed in the following example, grouped by their inclusion mode:

.kiro/steering/

# always - loaded in every session
product.md          what the pipeline is for
pipeline.md         the six-step build sequence and commands
structure.md        repo layout and the courses/<name>/ contract
tech.md             toolchain and required versions

# fileMatch - loaded when matching files are edited
scorm-invariants.md   invariants for scorm/src, build output, and course.yaml

# manual - deep guides, pulled in on demand
course-planning.md          plan modules and course.yaml
source-intake.md            convert raw source into lessons
lesson-authoring.md         write each lesson.md
scorm-authoring.md          build and package the SCORM zip
assessment-authoring.md     author an optional course assessment

Hooks automate the repetitive steps

Hooks run automatically as Kiro or the author works, so common checks don’t depend on someone remembering a command:

  • Lint on save – Editing any lesson.md or course.yaml re-lints that course immediately.
  • Validate on package creation – A new SCORM .zip file appearing under scorm/dist/ is validated the moment it’s built.
  • Steering reflection – After each turn, Kiro proposes updates to the steering guidance to capture best practices worth keeping for future course development.

Spec-driven development of new features

The repo includes a feature spec kept as a reference for how the pipeline was built. The page-dwell-gating spec added the feature that enforces a minimum time a learner must spend on a page before proceeding. After you understand the pipeline, you can extend it the same way, using the spec-driven development process in Kiro.

Walkthrough: Building a course

The following walkthrough takes you from an empty repo to an upload-ready SCORM package.

Prerequisites

  • Access to Kiro (IDE or kiro-cli).
  • Node.js 20+, Python 3.11+, and the zip command, with permission to install package dependencies (Kiro installs the project’s npm and pip packages during setup).
  • Raw training material to convert (slide decks, playbooks, and written docs).

Open the repo

Open the repository in Kiro. The workspace steering under .kiro/steering/ loads automatically, so Kiro already knows the pipeline commands, the repo layout, and the SCORM constraints.

Build the sample course

Building a course is a single prompt. In the Kiro chat panel, enter:

“Build the sample course.”

Kiro runs lint, build, and validate, and replies with the path to the upload-ready .zip file: courses/sample-course/scorm/dist/sample-course.zip.

Turn your own material into a course

For a new course, add your source material to courses/<name>/ and enter the following prompt:

“Plan and build a course from <name>.”

Kiro walks through planning course.yaml, authoring one lesson.md per module, and packaging.

Verify before you publish

You’ve already seen Kiro lint, build, and validate the package, and an included test checks the course’s progress tracking. The last check is a visual one. Serve the built course locally over HTTP to see it for yourself before uploading:

cd scorm/build    # the unzipped build output (same content as the .zip file)
python3 -m http.server 8080 # then open http://localhost:8080 in a browser

This serves the full built course locally. Figure 2 shows the course home page as a learner would see it.
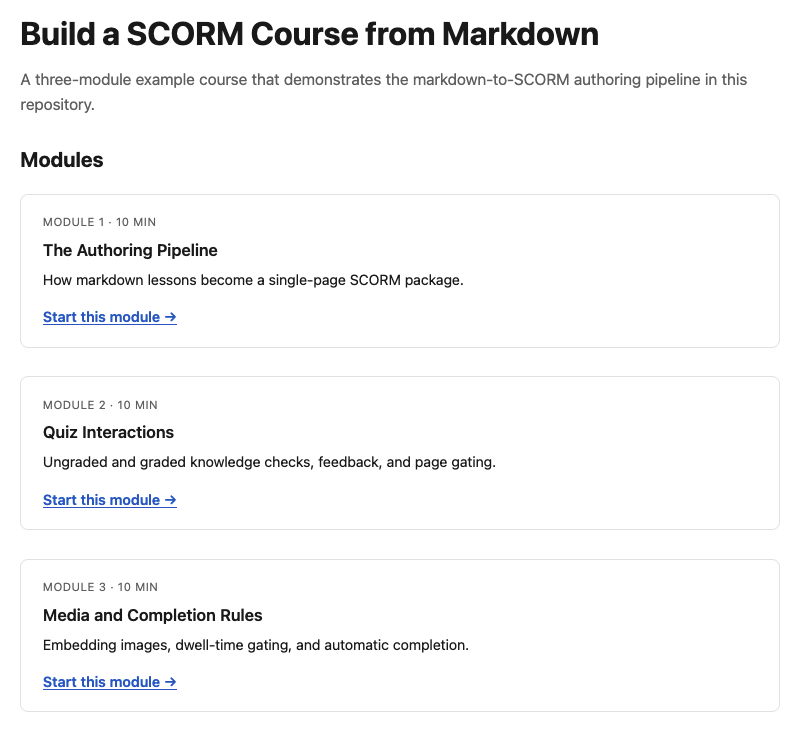
Screenshot of the sample course home page showing the course title, description, and three module cards.

Figure 2: Local preview of the sample course home page

The home page displays the course title, a short description, and a card for each module showing its number, estimated duration, a brief summary, and a link to start.

The final step is to upload the .zip file to your SCORM 1.2-compliant LMS to confirm end to end. Learning management systems vary. If you run into an issue, ask Kiro to help you troubleshoot it and learn the specifics of your LMS.

Cleaning up

There are no cloud resources to tear down because the pipeline runs entirely as local scripts and a Kiro session against your own repository. If you built the bundled sample course only to try the pipeline, you can safely delete courses/sample-course/scorm/dist/ and courses/sample-course/scorm/build/. Both are build output.

Conclusion

In this post, you saw how to turn raw training material into LMS-ready SCORM packages with Kiro. Authors stay focused on the course while Kiro handles the packaging. Because the pipeline lives in the repo as Steering, Specs, and Hooks, that expertise is version-controlled and reusable across every course and team.

To get started, clone the aws-samples repository, drop your source material into a course folder, and ask Kiro to build the course. To learn more, explore Kiro.


About the author

Omar Gonzalez

Omar Gonzalez

Omar is a Senior Solutions Architect at Amazon Web Services in Southern California with more than 20 years of experience in IT. He specializes in enterprise platforms, AI, and cloud transformation for financial services customers. Outside of work, he enjoys hiking and spending quality time with his family.

Amazon EMR on EC2 cost optimization: How a global financial services provider reduced costs by 30%

Post Syndicated from Omar Gonzalez original https://aws.amazon.com/blogs/big-data/amazon-emr-on-ec2-cost-optimization-how-a-global-financial-services-provider-reduced-costs-by-30/

In this post, we highlight key lessons learned while helping a global financial services provider migrate their Apache Hadoop clusters to AWS and best practices that helped reduce their Amazon EMR, Amazon Elastic Compute Cloud (Amazon EC2), and Amazon Simple Storage Service (Amazon S3) costs by over 30% per month.

We outline cost-optimization strategies and operational best practices achieved through a strong collaboration with their DevOps teams. We also discuss a data-driven approach using a hackathon focused on cost optimization along with Apache Spark and Apache HBase configuration optimization.

Background

In early 2022, a business unit of a global financial services provider began their journey to migrate their customer solutions to AWS. This included web applications, Apache HBase data stores, Apache Solr search clusters, and Apache Hadoop clusters. The migration included over 150 server nodes and 1 PB of data. The on-premises clusters supported real-time data ingestion and batch processing.

Because of aggressive migration timelines driven by the closure of data centers, they implemented a lift-and-shift rehosting strategy of their Apache Hadoop clusters to Amazon EMR on EC2, as highlighted in the Amazon EMR migration guide.

Amazon EMR on EC2 provided the flexibility for the business unit to run their applications with minimal changes on managed Hadoop clusters with the required Spark, Hive, and HBase software and versions installed. Because the clusters are managed, they were able to decompose their large on-premises cluster and deploy purpose-built transient and persistent clusters for each use case on AWS without increasing operational overhead.

Challenge

Although the lift-and-shift strategy allowed the business unit to migrate with lower risk and allowed their engineering teams to focus on product development, this came with increased ongoing AWS costs.

The business unit deployed transient and persistent clusters for different use cases. Several application components relied on Spark Streaming for real-time analytics, which was deployed on persistent clusters. They also deployed the HBase environment on persistent clusters.

After the initial deployment, they discovered several configuration issues that led to suboptimal performance and increased cost. Despite using Amazon EMR managed scaling for persistent clusters, the configuration wasn’t efficient due to setting a minimum of 40 core nodes and task nodes, resulting in wasted resources. Core nodes were also misconfigured to auto scale. This led to scale-in events shutting down core nodes with shuffle data. The business unit also implemented Amazon EMR auto-termination policies. Because of shuffle data loss on the EMR on EC2 clusters running Spark applications, certain jobs ran five times longer than planned. Here, auto-termination policies didn’t mark a cluster as idle because a job was still running.

Lastly, there were separate environments for development (dev), user acceptance testing (UAT), production (prod), which were also over-provisioned with the minimum capacity units for the managed scaling policies configured too high, leading to higher costs as shown in the following figure.

Short-term cost-optimization strategy

The business unit completed the migration of applications, databases, and Hadoop clusters in 4 months. Their immediate goal was to get out of their data centers as quickly as possible, followed by cost optimization and modernization. Although they expected greater upfront costs because of the lift-and-shift approach, their costs were 40% higher than forecasted. This sped up their need to optimize.

They engaged with their shared services team and the AWS team to develop a cost-optimization strategy. The business unit began by focusing on cost-optimization best practices to implement immediately that didn’t require product development team engagement or impact their productivity. They performed a cost analysis to determine the largest contributors of cost were EMR on EC2 clusters running Spark, EMR on EC2 clusters running HBase, Amazon S3 storage, and EC2 instances running Solr.

The business unit started by enforcing auto-termination of EMR clusters in their dev environments by using automation. They considered using Amazon EMR isIdle Amazon CloudWatch metrics to build an event-driven solution with AWS Lambda, as described in Optimize Amazon EMR costs with idle checks and automatic resource termination using advanced Amazon CloudWatch metrics and AWS Lambda. They implemented a stricter policy to shut down clusters in their lower environments after 3 hours, regardless of usage. They also updated managed scaling policies in DEV and UAT and set the minimum cluster size to three instances to allow clusters to scale up as needed. This resulted in a 60% savings in monthly dev and UAT costs over 5 months, as shown in the following figure.

For the initial production deployment, they had a subset of Spark jobs running on a persistent cluster with an older Amazon EMR 5.(x) release. To optimize costs, they split smaller jobs and larger jobs to run on separate persistent clusters and configured the minimum number of core nodes required to support jobs in each cluster. Setting the core nodes to a constant size while using managed scaling for only task nodes is a recommended best practice and eliminated the issue of shuffle data loss. This also improved the time to scale in and out, because task nodes don’t store data in Hadoop Distributed File System (HDFS).

Solr clusters ran on EC2 instances. To optimize this environment, they ran performance tests to determine the best EC2 instances for their workload.

With over one petabyte of data, Amazon S3 contributed to over 15% of monthly costs. The business unit enabled the Amazon S3 Intelligent-Tiering storage class to optimize storage expenses for historical data and reduce their monthly Amazon S3 costs by over 40%, as shown in the following figure. They also migrated Amazon Elastic Block Store (Amazon EBS) volumes from gp2 to gp3 volume types.

Longer-term cost-optimization strategy

After the business unit realized initial cost savings, they engaged with the AWS team to organize a financial hackathon (FinHack) event. The goal of the hackathon was to reduce costs further by using a data-driven process to test cost-optimization strategies for Spark jobs. To prepare for the hackathon, they identified a set of jobs to test using different Amazon EMR deployment options (Amazon EC2, Amazon EMR Serverless) and configurations (Spot, AWS Graviton, Amazon EMR managed scaling, EC2 instance fleets) to arrive at the most cost-optimized solution for each job. A sample test plan for a job is shown in the following table. The AWS team also assisted with analyzing Spark configurations and job execution during the event.

Job Test Description Configuration
Job 1 1 Run an EMR on EC2 job with default Spark configurations Non Graviton, On-Demand Instances
2 Run an EMR on Serverless job with default Spark configurations Default configuration
3 Run an EMR on EC2 job with default Spark configuration and Graviton instances Graviton, On-Demand Instances
4 Run an EMR on EC2 job with default Spark configuration and Graviton instances. Hybrid Spot Instance allocation. Graviton, On-Demand and Spot Instances

The business unit also performed extensive testing using Spot Instances before and during the FinHack. They initially used the Spot Instance advisor and Spot Blueprints to create optimal instance fleet configurations. They automated the process to select the most optimal Availability Zone to run jobs by querying for the Spot placement scores using the get_spot_placement_scores API before launching new jobs.

During the FinHack, they also developed an EMR job tracking script and report to granularly track cost per job and measure ongoing improvements. They used the AWS SDK for Python (Boto3) to list the status of all transient clusters in their account and report on cluster-level configurations and instance hours per job.

As they executed the test plan, they found several additional areas of enhancement:

  • One of the test jobs makes API calls to Solr clusters, which introduced a bottleneck in the design. To prevent Spark jobs from overwhelming the clusters, they fine-tuned executor.cores and spark.dynamicAllocation.maxExecutors properties.
  • Task nodes were over-provisioned with large EBS volumes. They reduced the size to 100 GB for additional cost savings.
  • They updated their instance fleet configuration by setting unit/weights proportional based on instance types selected.
  • During the initial migration, they set the spark.sql.shuffle.paritions configuration too high. The configuration was fine-tuned for their on-premises cluster but not updated to align with their EMR clusters. They optimized the configuration by setting the value to one or two times the number of vCores in the cluster .

Following the FinHack, they enforced a cost allocation tagging strategy for persistent clusters that are deployed using Terraform and transient clusters deployed using Amazon Managed Workflows for Apache Airflow (Amazon MWAA). They also deployed an EMR Observability dashboard using Amazon Managed Service for Prometheus and Amazon Managed Grafana.

Results

The business unit reduced monthly costs by 30% over 3 months. This allowed them to continue migration efforts of remaining on-premises workloads. Most of their 2,000 jobs per month now run on EMR transient clusters. They have also increased AWS Graviton usage to 40% of total usage hours per month and Spot usage to 10% in non-production environments.

Conclusion

Through a data-driven approach involving cost analysis, adherence to AWS best practices, configuration optimization, and extensive testing during a financial hackathon, the global financial services provider successfully reduced their AWS costs by 30% over 3 months. Key strategies included enforcing auto-termination policies, optimizing managed scaling configurations, using Spot Instances, adopting AWS Graviton instances, fine-tuning Spark and HBase configurations, implementing cost allocation tagging, and developing cost tracking dashboards. Their partnership with AWS teams and a focus on implementing short-term and longer-term best practices allowed them to continue their cloud migration efforts while optimizing costs for their big data workloads on Amazon EMR.

For additional cost-optimization best practices, we recommend visiting AWS Open Data Analytics.


About the Authors

Omar Gonzalez is a Senior Solutions Architect at Amazon Web Services in Southern California with more than 20 years of experience in IT. He is passionate about helping customers drive business value through the use of technology. Outside of work, he enjoys hiking and spending quality time with his family.
Navnit Shukla, an AWS Specialist Solution Architect specializing in Analytics, is passionate about helping clients uncover valuable insights from their data. Leveraging his expertise, he develops inventive solutions that empower businesses to make informed, data-driven decisions. Notably, Navnit Shukla is the accomplished author of the book Data Wrangling on AWS, showcasing his expertise in the field. He also runs the YouTube channel Cloud and Coffee with Navnit, where he shares insights on cloud technologies and analytics. Connect with him on LinkedIn.

Using Experian identity resolution with AWS Clean Rooms to achieve higher audience activation match rates

Post Syndicated from Omar Gonzalez original https://aws.amazon.com/blogs/big-data/using-experian-identity-resolution-with-aws-clean-rooms-to-achieve-higher-audience-activation-match-rates/

This is a guest post co-written with Tyler Middleton, Experian Senior Partner Marketing Manager, and Jay Rakhe, Experian Group Product Manager.

As the data privacy landscape continues to evolve, companies are increasingly seeking ways to collect and manage data while protecting privacy and intellectual property. First party data is more important than ever for companies to understand their customers and improve how they interact with them, such as in digital advertising across channels. Companies are challenged with having a complete view of their customers as they engage with them across different channels and devices, in addition to other third parties that could complement their data to generate rich insights about their customers. This has driven companies to build identity graph solutions or use well-known identity resolution from providers such as Experian. It has also driven companies to grow their first-party consumer-consented data and collaborate with other companies and partners to create better-informed advertising campaigns.

AWS Clean Rooms allows companies to collaborate securely with their partners on their collective datasets without sharing or copying one another’s underlying data. Combining Experian’s identity resolution with AWS Clean Rooms can help you achieve higher match rates with your partners on your collective datasets when you run an AWS Clean Rooms collaboration. You can achieve higher match rates by using Experian’s diverse offline and digital ID database.

In this post, we walk through an example of a retail advertiser collaborating with a connected television (CTV) provider, facilitated by AWS Clean Rooms and Experian. AWS Clean Rooms facilitates a secure collaboration for an audience activation use case.

Use case overview

Retail advertisers recognize the growing consumer behaviors to use streaming TV services over traditional TV channels. Because of this, you may want to use your customer tiering and past purchase history datasets to target your audience in CTV.

The following example advertiser dataset includes the audience to be targeted on the CTV platform.

Advertiser

ID

First Last Address City State Zip Customer Tier LTV Last Purchase Date
123 Tyler Smith 4128 Et Street Franklin OK 82736 Gold $823 8/1/21
456 Karleigh Jones 2588 Nibh Street Clinton RI 38947 Gold $741 2/2/22
984 Alex Brown 6556 Tincidunt Avenue Madison WI 10975 Silver $231 1/17/22

The following sample CTV provider dataset has email addresses and subscription status.

Email Address Status
[email protected] Subscribed
[email protected] Free Ad Tier
[email protected] Trial

Experian performs identity resolution on each dataset by matching against Experian’s attributes on 250 million consumers and 126 million households. Experian assigns a unique and synthetic Experian ID referred to as a Living Unit ID (LUID) to each matched record.

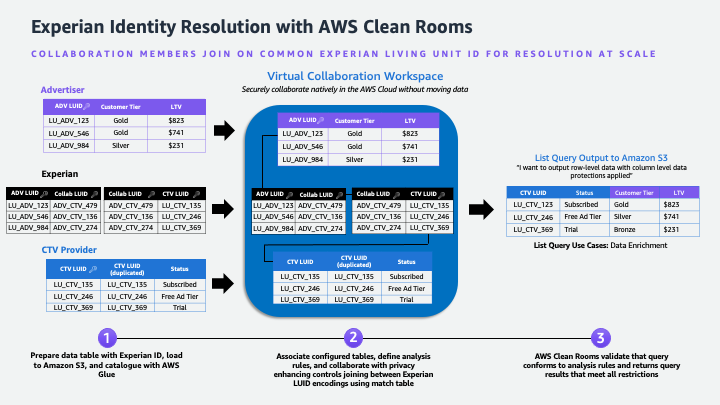
The Experian LUIDs for an advertiser and CTV provider are unique per consumer record. For example, LU_ADV_123 in the advertiser table corresponds to LU_CTV_135 in the CTV table. To allow the CTV provider and advertiser to match identities across the datasets, Experian generates a collaboration LUID, as shown in the following figure. This allows a double-blind join to be performed against both tables in AWS Clean Rooms.

 Advertiser and CTV Provider Double Blind Join

The following figure illustrates the workflow in our example AWS Clean Rooms collaboration.

Experian identity resolution with AWS Clean Rooms workflow

We walk you through the following high-level steps:

  1. Prepare the data tables with Experian IDs, load the data to Amazon Simple Storage Service (Amazon S3), and catalog the data with AWS Glue.
  2. Associate the configured tables, define the analysis rules, and collaborate with privacy-enhancing controls joining between the Experian LUID encodings using the match table.
  3. Use AWS Clean Rooms to validate that the query conforms to the analysis rules and returns query results that meet all restrictions.

Prepare data tables with Experian IDs, load data to Amazon S3, and catalog data with AWS Glue

First, the advertiser and CTV provider engage with Experian directly to assign Experian LUIDs to their consumer records. During this process, both parties provide identity components to Experian as an input. Experian processes their input data and returns an Experian LUID when a matched identity is found. New and existing Experian customers can start this process by reaching out to Experian Marketing Services.

After the tables are prepared with Experian LUIDs, the advertiser, CTV provider, and Experian join an AWS Clean Rooms collaboration. A collaboration is a secure logical boundary in AWS Clean Rooms in which members perform SQL queries on configured tables. Any participant can create an AWS Clean Rooms collaboration. In this example, the CTV provider has created a collaboration in AWS Clean Rooms and invited the advertiser and Experian to join and contribute data, without sharing their underlying data with each other. The advertiser and Experian will log in to each of their respective AWS accounts and join the collaboration as a member.

The next step is to upload and catalog the data to be queried in AWS Clean Rooms. Each collaborator will upload their dataset to Amazon S3 object storage in their respective accounts. Next, the data is cataloged in the AWS Glue Data Catalog.

Associate the configured tables, define analysis rules, and collaborate with privacy enhancing controls

After the table is cataloged in the AWS Glue Data Catalog, it can be associated with an AWS Clean Rooms configured table. A configured table defines which columns can be used in the collaboration and contains an analysis rule that determines how the data can be queried.

In this step, Experian adds two configured tables that include the collaboration LUIDs that allow the CTV provider and advertiser to match across their datasets.

The advertiser has defined a list analysis rule that allows the CTV provider to run queries that return a row-level list of the collective data. They have also configured their unique Experian advertiser LUIDs as the join keys. In AWS Clean Rooms, join key columns can be used to join datasets, but the values can’t be returned in the result.

{
 "joinColumns": [
   "experian_luid_adv"
 ],
 "listColumns": [
   "ltv",
   "customer_tier"
 ]
}

The CTV provider can perform queries against the datasets. They must duplicate the CTV LUID column to use it as a join key and query dimension, as shown in the following code. This is an important step when configuring a collaboration with Experian as an ID provider.

{
 "joinColumns": [
   "experian_luid_ctv"
 ],
 "listColumns": [
   "experian_luid_ctv_2",
   "sub_status"
 ]
}

Use AWS Clean Rooms to validate the query matches the analysis rule type, expected query structure, and columns and tables defined in the analysis rule

The CTV provider can now perform a SQL query against the datasets using the AWS Clean Rooms console or the AWS Clean Rooms StartProtectedQuery API.

The following sample list query returns the customer tier and LTV (lifetime value) for matched CTV identities:

SELECT DISTINCT ctv.experian_luid_ctv_2,
       ctv.sub_status,
       adv.customer_tier,
       adv.ltv
FROM ctv
   JOIN experian_ctv
       ON ctv.experian_luid_ctv = experian_ctv.experian_luid_ctv
   JOIN experian_adv
       ON experian_ctv.experian_luid_collab = experian_adv.experian_luid_collab
   JOIN adv
       ON experian_adv.experian_luid_adv = adv.experian_luid_adv

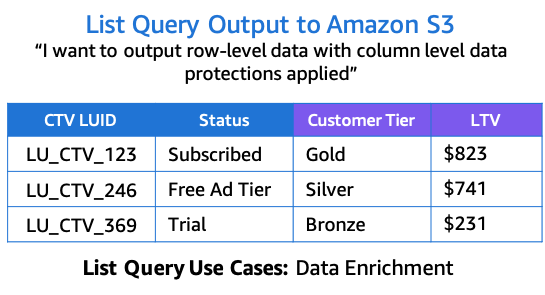
The following figure illustrates the results.

AWS Clean Rooms List Query Output

Conclusion

In this post, we showed how a retail advertiser can enrich their data with CTV provider data using Experian in an AWS Clean Rooms collaboration, without sharing or exposing raw data with each other. The advertiser can now use the CTV customer tiering and subscription data to activate specific segments on the CTV platform. For example, if the retail advertiser wants to offer membership to their loyalty program, they can now target their high LTV customers that have a CTV paid subscription. With AWS Clean Rooms, this use case can be expanded further to include additional collaborators to further enrich your data. AWS Clean Rooms partners include identity resolution providers, such as Experian, who can help you more easily join data using Experian identifiers. To learn more about the benefits of Experian identity resolution, refer to Identity resolution solutions. New and existing customers can contact Experian Marketing Services to authorize an AWS Clean Rooms collaboration. Visit the AWS Clean Rooms User Guide to get started using AWS Clean Rooms today.


About the Authors

Omar Gonzalez is a Senior Solutions Architect at Amazon Web Services in Southern California with more than 20 years of experience in IT. He is passionate about helping customers drive business value through the use of technology. Outside of work, he enjoys hiking and spending quality time with his family.

Matt Miller is a Business Development Principal at AWS. In his role, Matt drives customer and partner adoption for the AWS Clean Rooms service specializing in advertising and marketing industry use cases. Matt believes in the primacy of privacy enhanced data collaboration and interoperability underpinning data-driven marketing imperatives from customer experience to addressable advertising. Prior to AWS, Matt led strategy and go-to market efforts for ad technologies, large agencies, and consumer data products purpose-built to inform smarter marketing and deliver better customer experiences.