All posts by Praveen Kumar

Get to insights faster using Notebooks in Amazon SageMaker Unified Studio

Post Syndicated from Praveen Kumar original https://aws.amazon.com/blogs/big-data/get-to-insights-faster-using-notebooks-in-amazon-sagemaker-unified-studio/

In this post, we demonstrate how Notebooks in Amazon SageMaker Unified Studio help you get to insights faster by simplifying infrastructure configuration. You’ll see how to analyze housing price data, create scalable data tables, run distributed profiling, and train machine learning (ML) models within a single notebook environment.

Data scientists and analysts often spend days configuring infrastructure and managing authentication across multiple data sources before they can begin analysis. When working with data across Amazon Simple Storage Service (Amazon S3), Amazon Redshift, Snowflake, and local files, teams face repeated authentication setup, manual compute scaling decisions, and tool-switching overhead that delays insights.

Notebooks in Amazon SageMaker Unified Studio provide instant access to 12+ data sources, compute scaling from local to distributed processing, and AI-powered code generation within a single browser-based environment. You’ll learn to use polyglot programming, multi-engine compute, and AI-assisted development to accelerate your path from question to insight.

What are Notebooks in Amazon SageMaker Unified Studio?

Notebooks in Amazon SageMaker Unified Studio provide an interactive environment for data analysis, exploration, engineering, and machine learning workflows. It delivers five integrated capabilities:

  • Polyglot programming: Write code in Python and SQL interchangeably within the same notebook environment
  • Unified data access: Connect instantly to data stored in Amazon S3, AWS Glue Data Catalog, Apache Iceberg tables, and third-party sources like Snowflake and BigQuery
  • Native visualization: Create charts directly from Python and SQL results for immersive data analytics
  • AI-powered development: Generate code through natural language prompts using SageMaker Data Agent, with an intelligent chat interface for data analytics, data science, and ML tasks
  • Flexible compute: Scale from basic instances to GPU-powered environments as your needs grow

Architecture

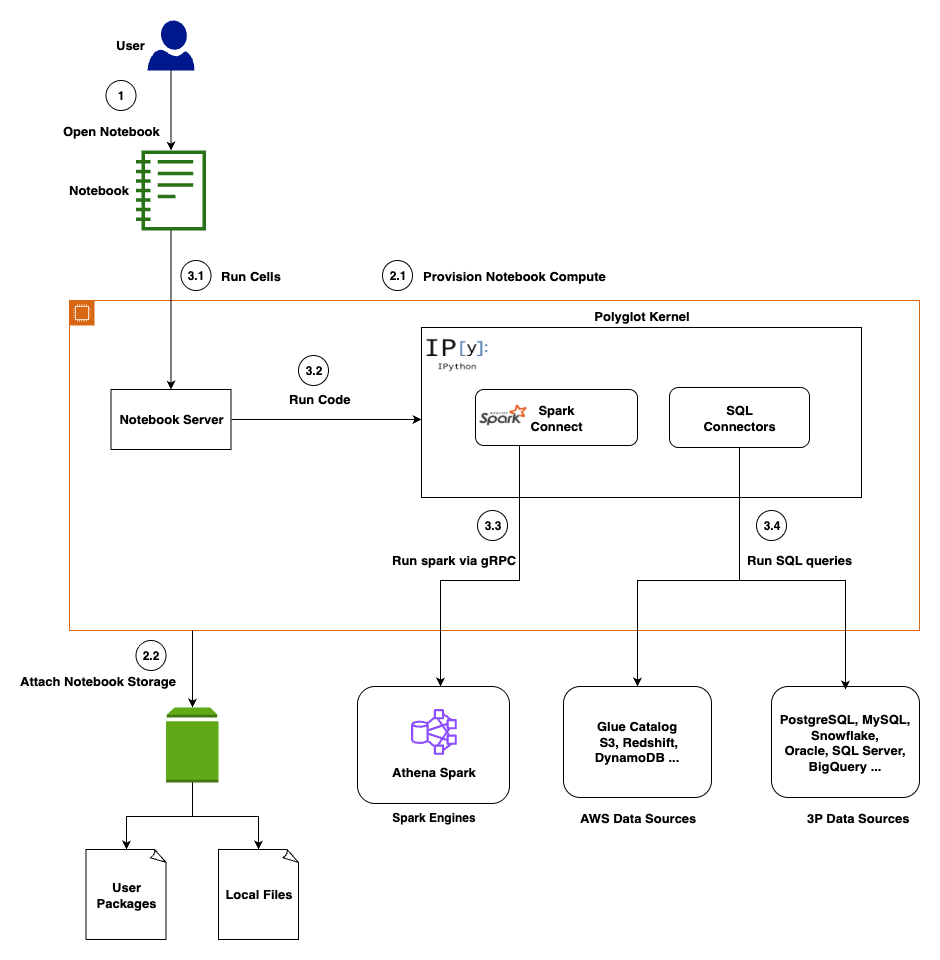
This section covers the architecture of Notebooks, which delivers enterprise-scale analytics with browser-based simplicity through a cloud-native architecture that integrates multiple compute engines, diverse data sources, and AI-powered assistance.
Presentation layer

You access the notebook interface through Amazon SageMaker Unified Studio, interacting with a familiar interface featuring code cells for execution, markdown cells for documentation, and visualization cells for charts and tables.

Compute layer

A dedicated notebook server manages your kernel lifecycle and session state. Key components include a Language Server for code completion, a Python 3.11 runtime with pre-loaded data science libraries, and a Polyglot Kernel that handles your Python, PySpark, and SQL execution within the same notebook. Persistent Amazon Elastic Block Store (Amazon EBS) storage backs each notebook you create.

Execution layer

Notebooks support multiple execution engines, automatically routing your code to the optimal processing engine. In-memory execution handles your smaller datasets and rapid prototyping. Apache Spark via Amazon Athena provides distributed processing for your large-scale analytics via Spark Connect. Native connectivity to Amazon Athena (Trino), Amazon Redshift, Snowflake, and BigQuery processes your SQL queries.

Data Integration

You get unified access to 12+ data sources including AWS-native (Amazon S3, AWS Glue, Amazon Athena, Amazon Redshift) and third-party (Snowflake, BigQuery, PostgreSQL, MySQL) data sources. For the latest supported data sources, see Connect to data sources .

AI layer

The SageMaker Data Agent operates in two modes to assist you: an Agent Panel for multi-step analytical workflows and Inline Assistance for focused, cell-level code generation. For a detailed overview, see Accelerate context-aware data analysis and ML workflows with Amazon SageMaker Data Agent .

Security is embedded throughout the architecture to protect your work. Data access respects your AWS Identity and Access Management (AWS IAM) permissions. The notebook and the agent can only access data sources you’re authorized to use. Communication between components uses encrypted channels, and your notebook storage is encrypted at rest. The AI agent includes built-in guardrails to help prevent destructive operations and logs interactions for your compliance and auditing purposes.

Prerequisites

Before you begin, you need:

  • An AWS account with appropriate permissions to create Amazon SageMaker Unified Studio resources. See Set up IAM-based domains for complete permission requirements.
  • Basic familiarity with Python programming and SQL queries
  • Understanding of data analysis concepts and ML workflows
  • Access to the sample housing dataset (provided in the walkthrough)

Getting started with Notebooks

To get started, open the Amazon SageMaker console and choose Get started.
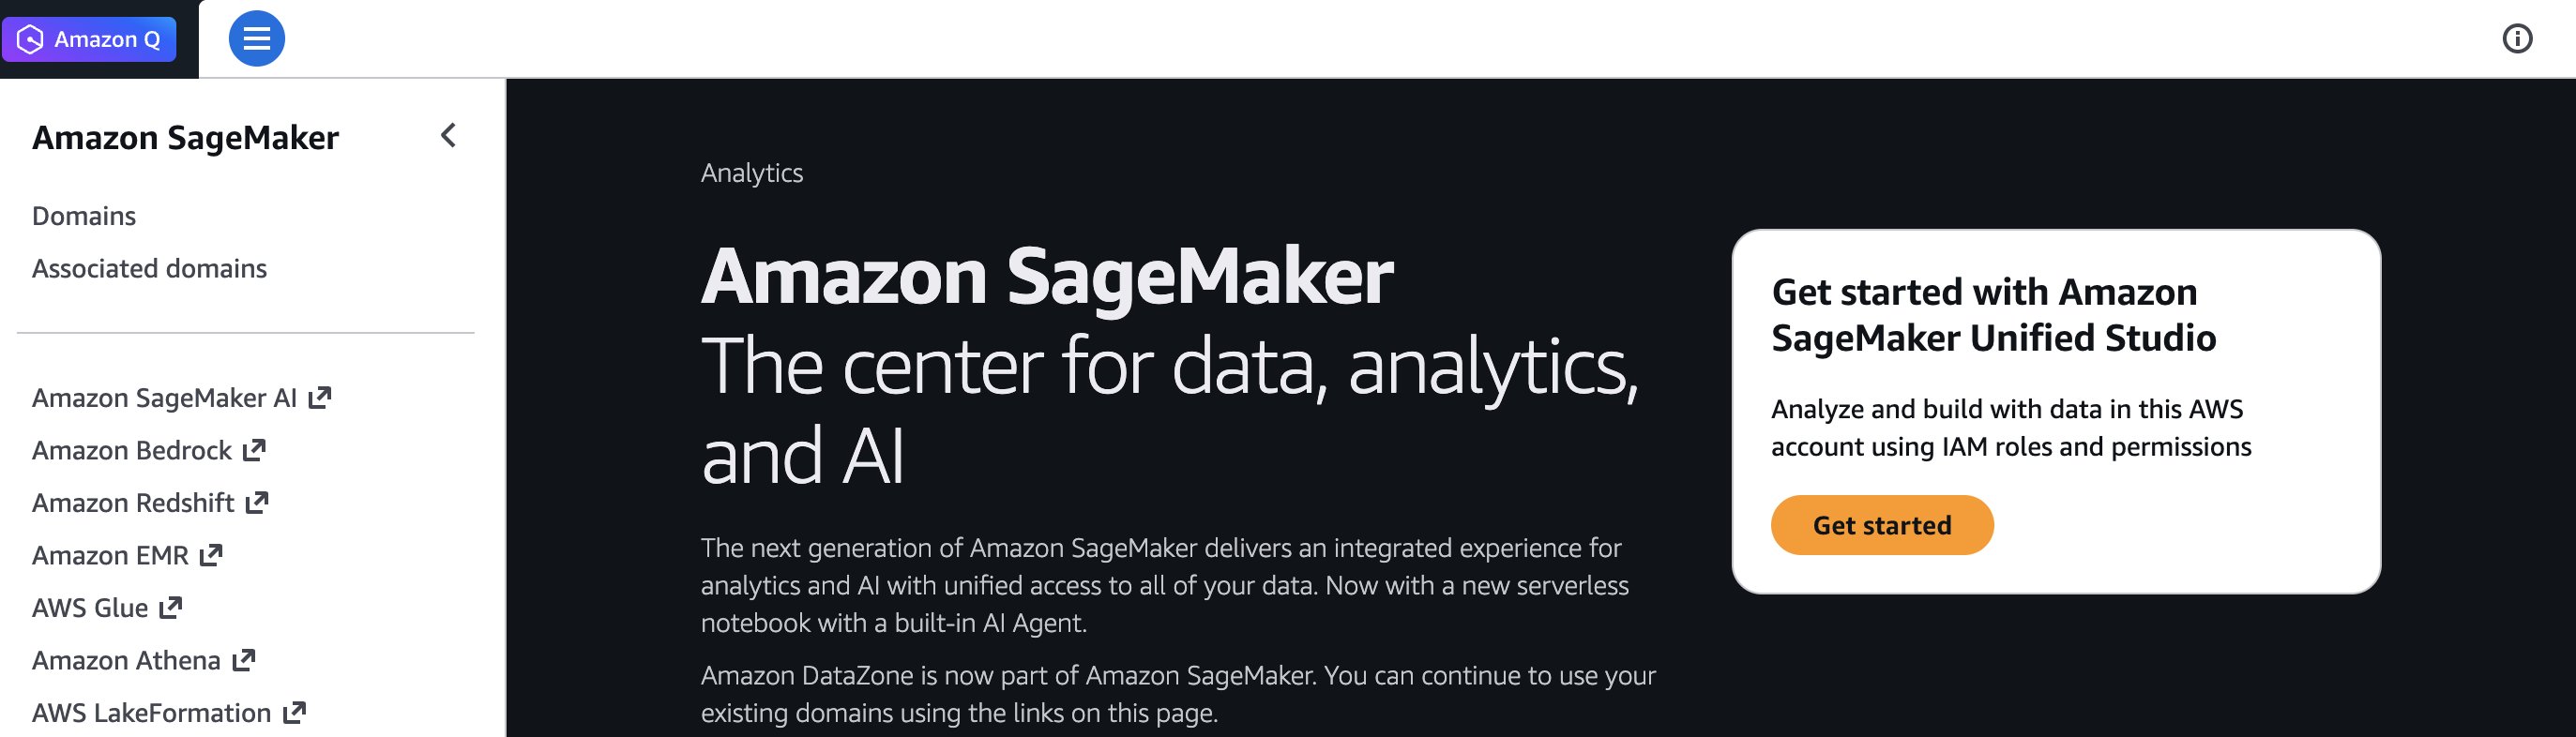
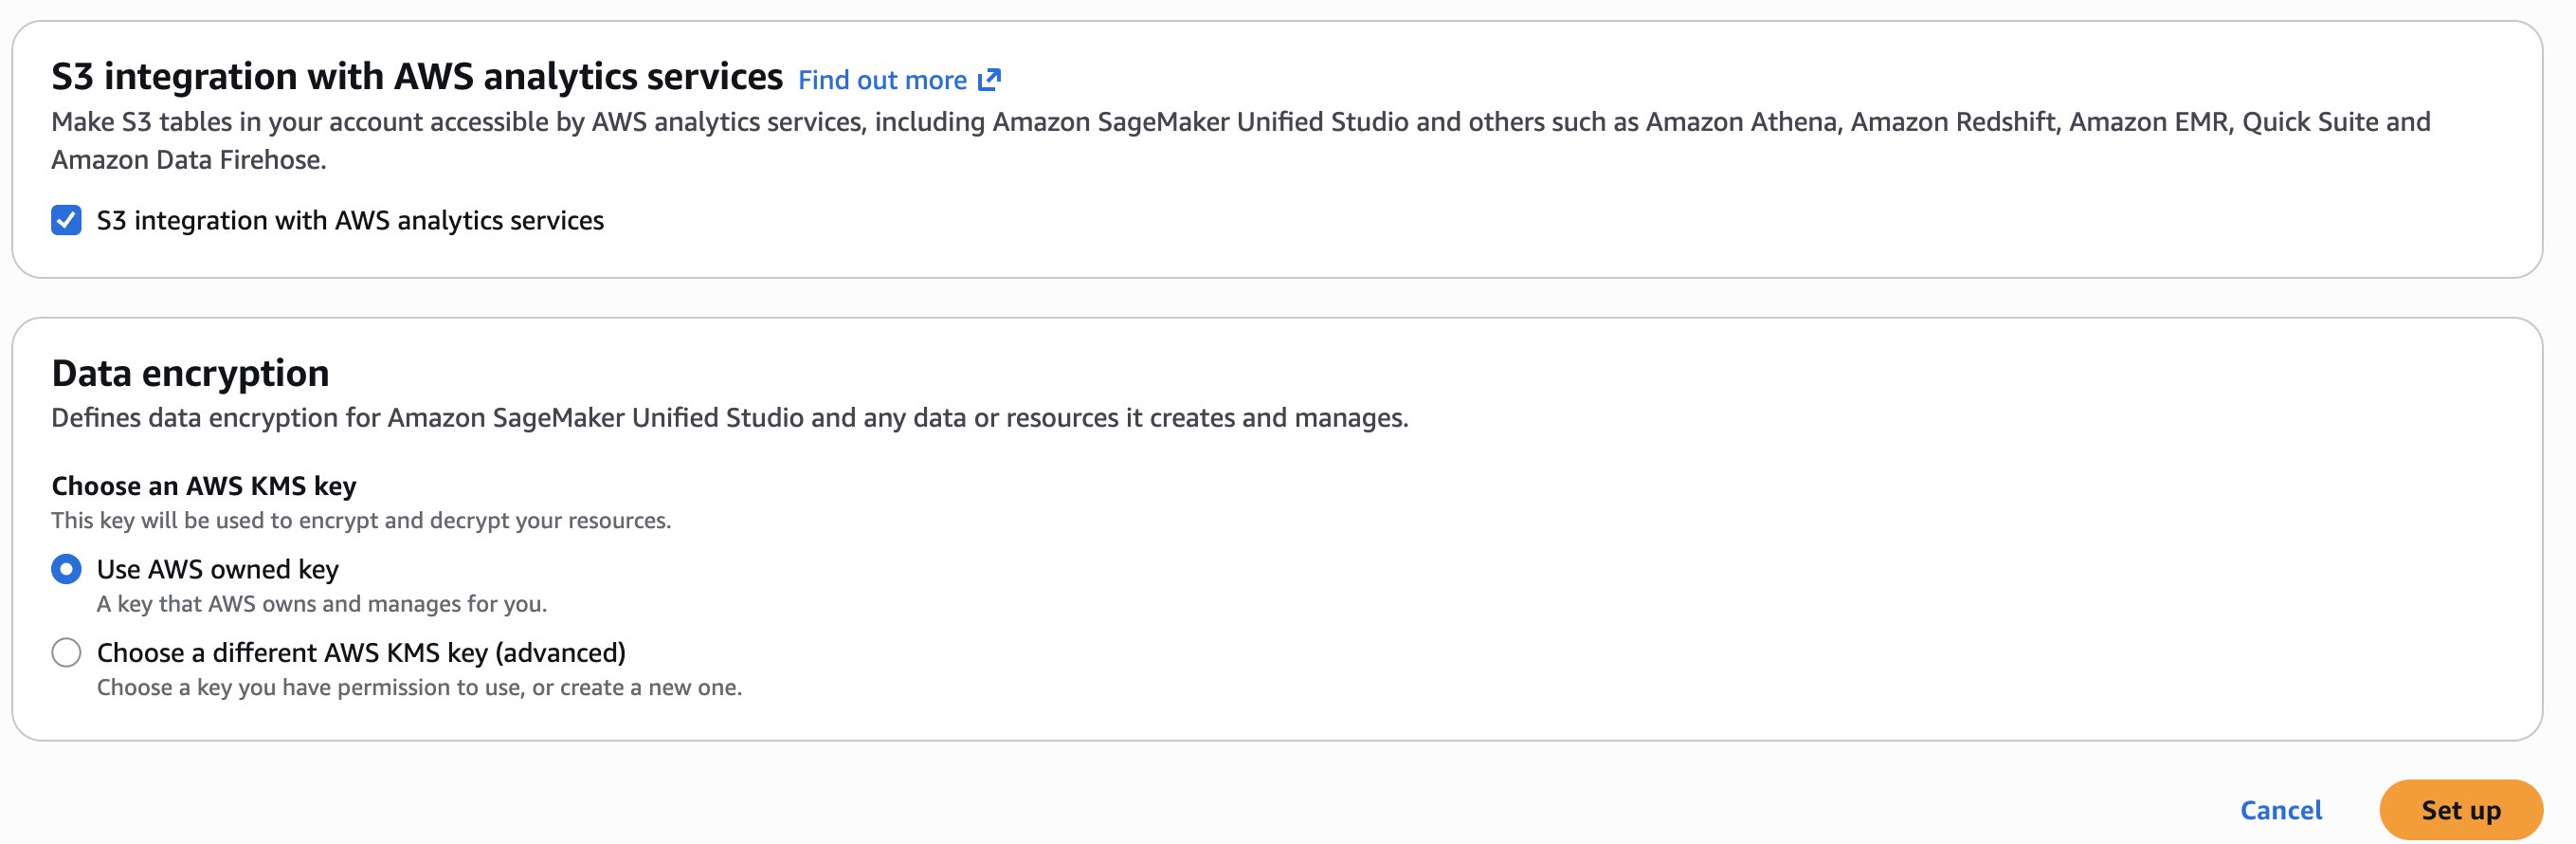
You will be prompted either to select an existing AWS Identity and Access Management (AWS IAM) role that has access to your data and compute, or to create a new role. For this walkthrough, choose Create a new role and leave the other options at their defaults.

Choose Set up. It takes a few minutes to complete your environment.
Use case

In this post, you’ll use a Notebook and the SageMaker Data Agent to perform the following:

  1. Working with dataset: Upload sample dataset housing.csv and explore with data explorer
  2. Polyglot programming: Query dataframes with SQL via DuckDB
  3. Multi-engine access via AWS Glue: Create an AWS Glue table to unlock Athena SQL/Spark engines for distributed processing
  4. Advanced analytics: Use Athena Spark for data profiling
  5. AI-assisted development: Generate profiling and ML code with Data Agent
  6. ML workflow: Train Random Forest model and evaluate results

First, let’s walk through the interface and explore its core capabilities.

Understanding the interface

The Notebooks interface follows familiar notebook conventions with cells for code execution and markdown for documentation. Within the notebook, you’ll see your current programming environment (such as Python 3.11) and compute profile specifications. The interface allows you to:

  • Access your data by browsing files, exploring data catalogs, and managing third-party connections
  • Monitor variables created within your notebook context
  • Scale compute resources on demand by adjusting virtual CPUs and RAM based on your workload requirements, even scaling up to GPU instances
  • Manage packages by installing and configuring Python packages as needed

Working with the dataset

For this walkthrough, you’ll use the housing.csv sample dataset which you can download from this page. (the file is named canvas-sample-housing.csv on the linked page). Choose the Files icon in the left panel and choose the Local tab. Upload the CSV file to the notebook on the Local tab.
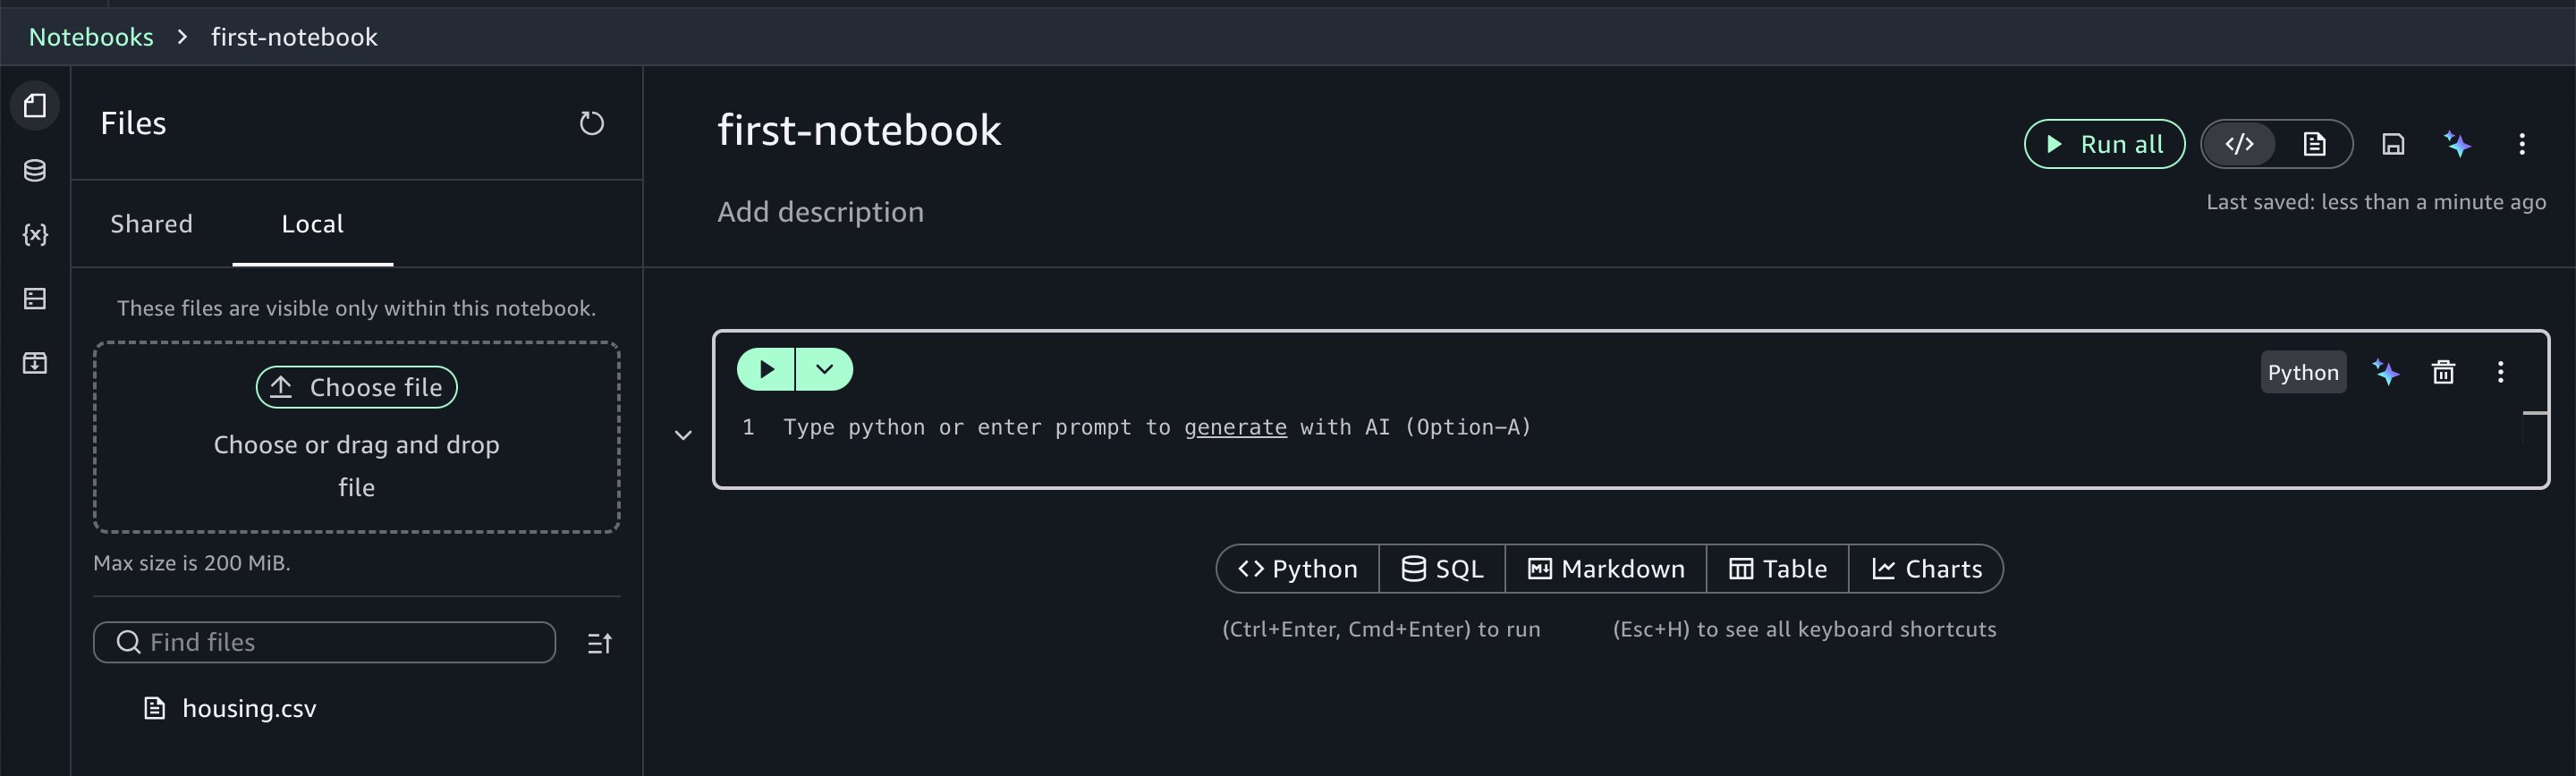
Notebooks provide you with instant access to your data assets. Using the data explorer, you can browse your AWS Glue Data Catalog, Amazon S3 table catalogs, Amazon S3 buckets, and configured third-party connections.

Choose the three-dot options menu.
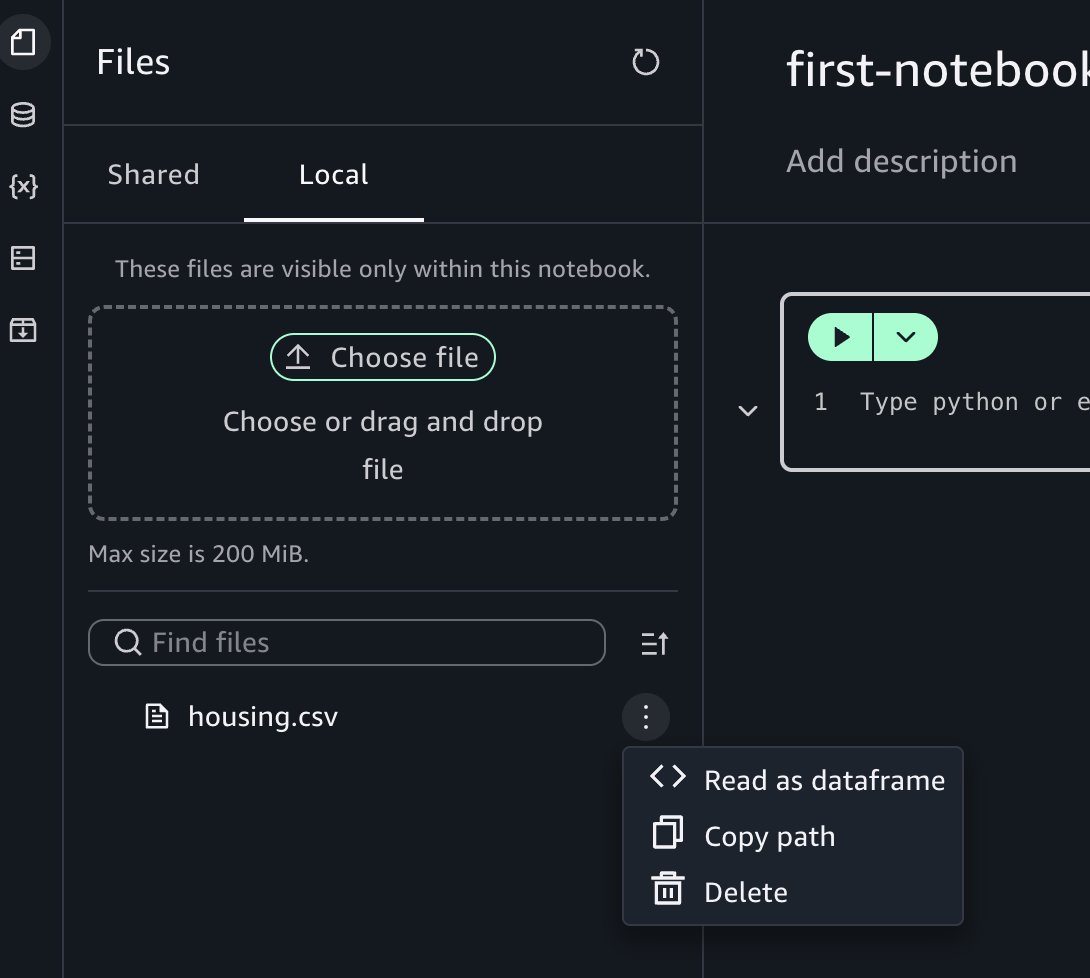
Choose Read as dataframe, then run the inserted cell in the notebook to view the results.
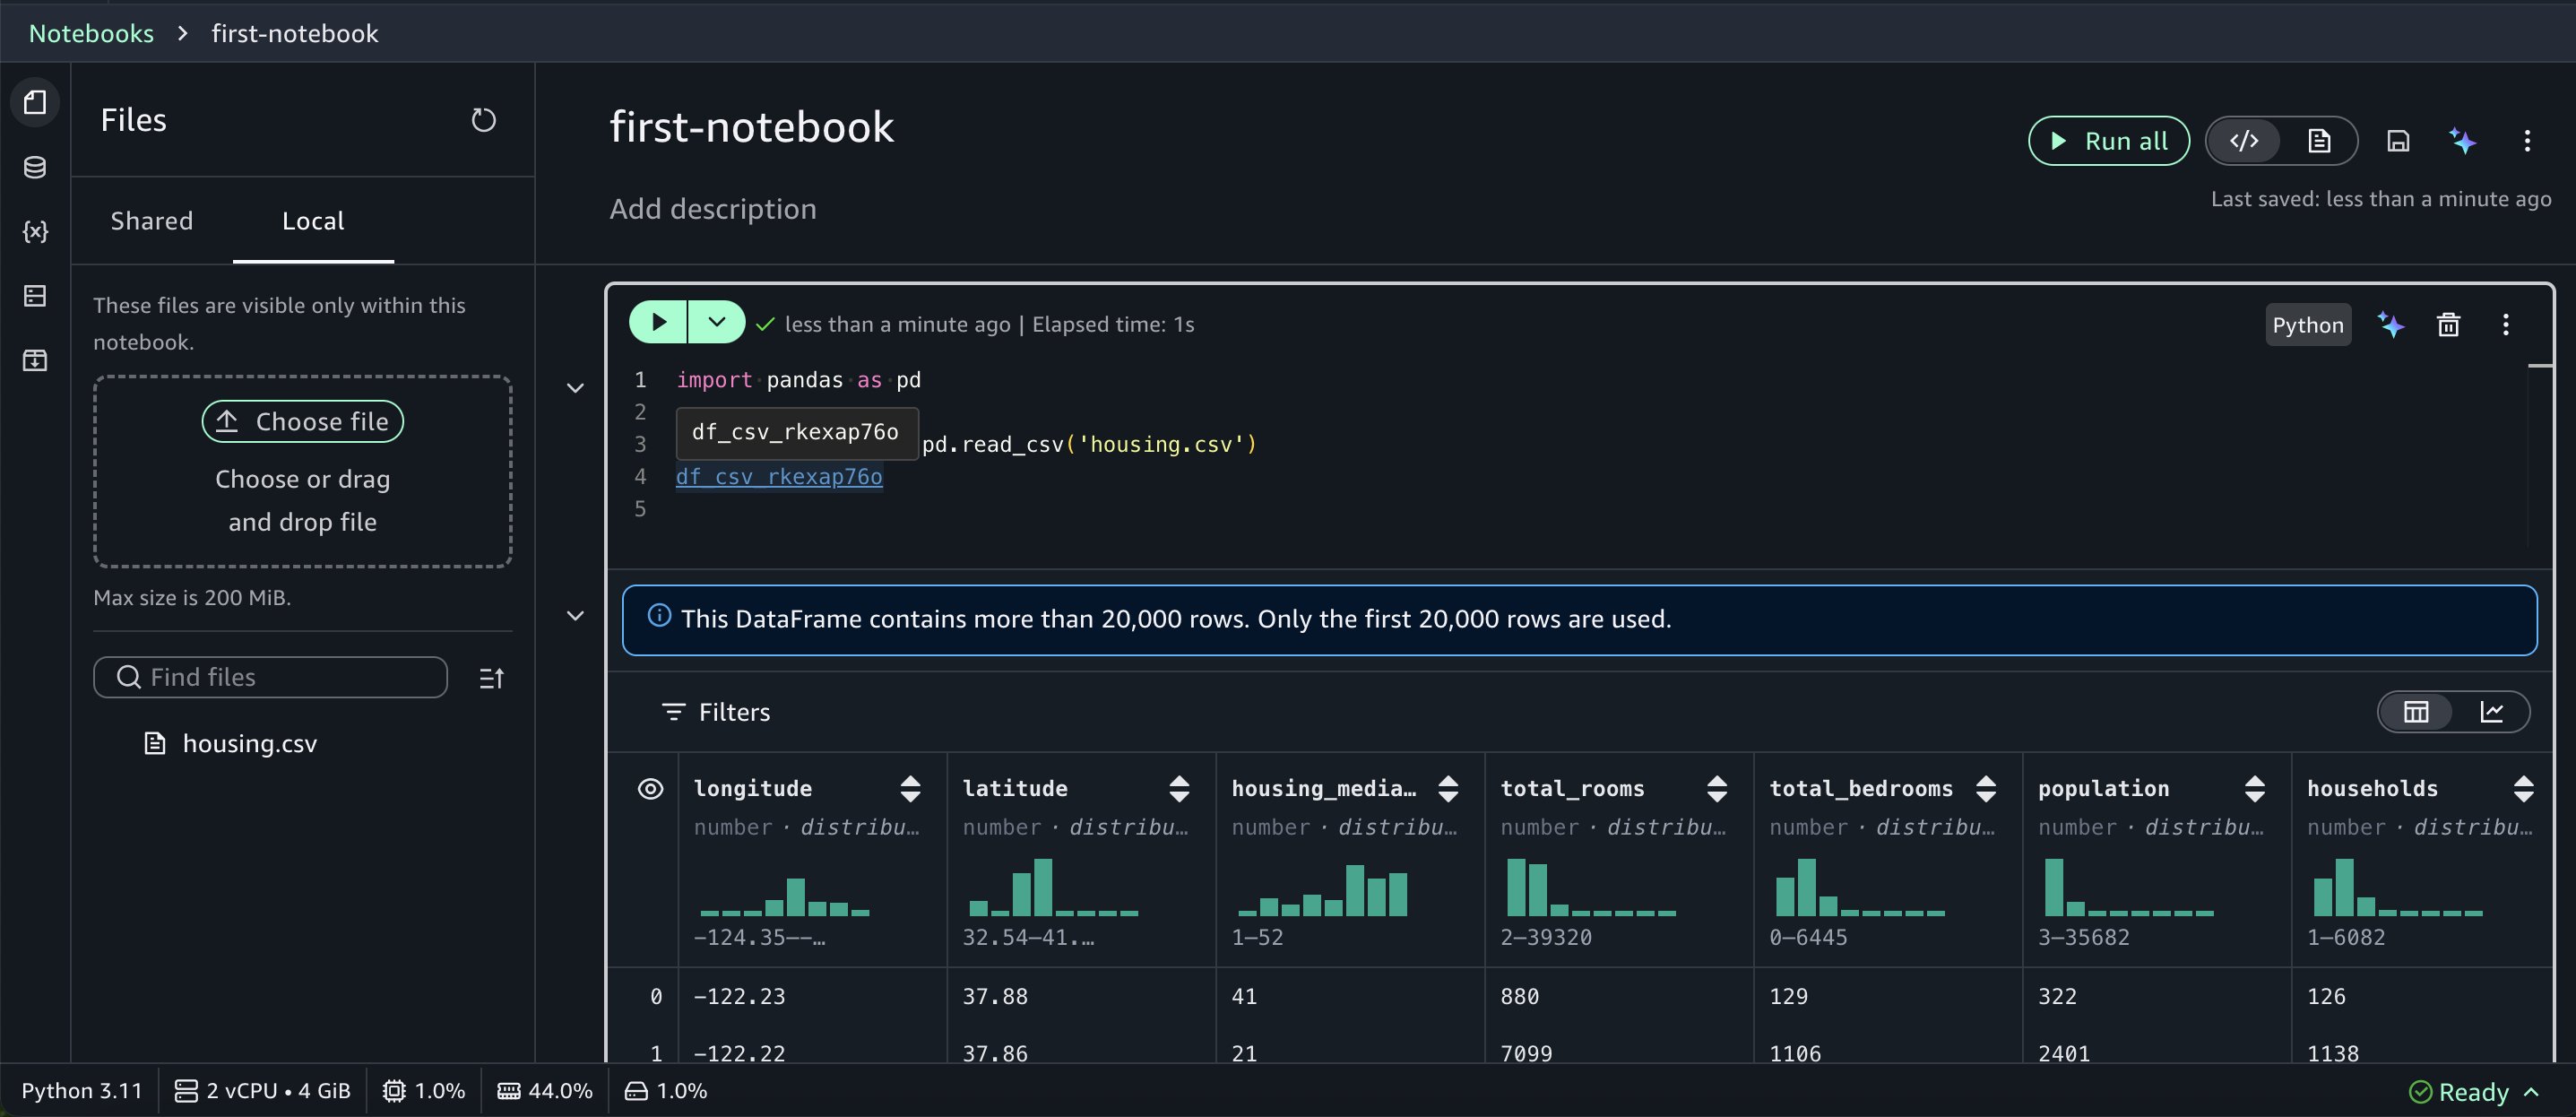
import pandas as pd
<<df_csv_xxxx>> = pd.read_csv('housing.csv')
<<df_csv_xxxx>>

When you return a dataframe, Notebooks render it in a rich table format with automatic data profiling.

Polyglot programming: Python and SQL together

One of the most powerful features in Notebooks is the interoperability between Python and SQL. After you load data into a Python dataframe, you can immediately query it using SQL. For example, to calculate total population and household by ocean proximity, you can run:
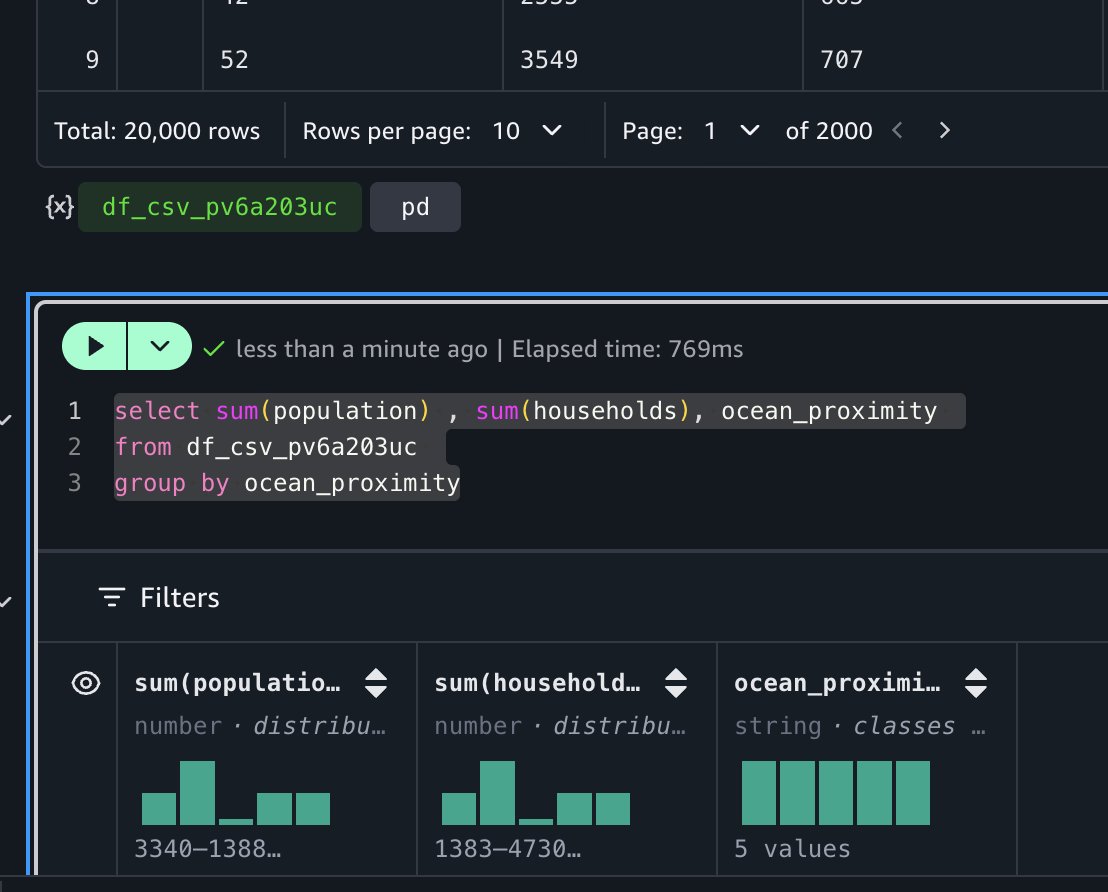
select sum(population) ,sum(households),ocean_proximity 
from<<df_csv_xxxx>> 
group byocean_proximity

The notebook’s autocomplete functionality recognizes dataframes in your context, making SQL queries intuitive.

This SQL query runs on DuckDB (an in-memory SQL database engine), which requires no separate installation or server maintenance on your part. DuckDB’s lightweight design integrates into Python, Java, and other environments, making it ideal for your rapid interactive data analysis. For distributed processing needs, you can use engines such as Apache Spark or Trino after creating an AWS Glue table for this dataset.

Create an AWS Glue table for the dataset

After you create an AWS Glue table, you can query the dataset using various AWS Glue catalog-compatible engines, including Amazon Athena SQL (Trino) and Amazon Athena Spark. These engines deliver optimal price-performance for your specific workload requirements.

Start by creating an AWS Glue database. To do that, create a new cell in the notebook by choosing SQL and selecting Amazon Athena (SQL).
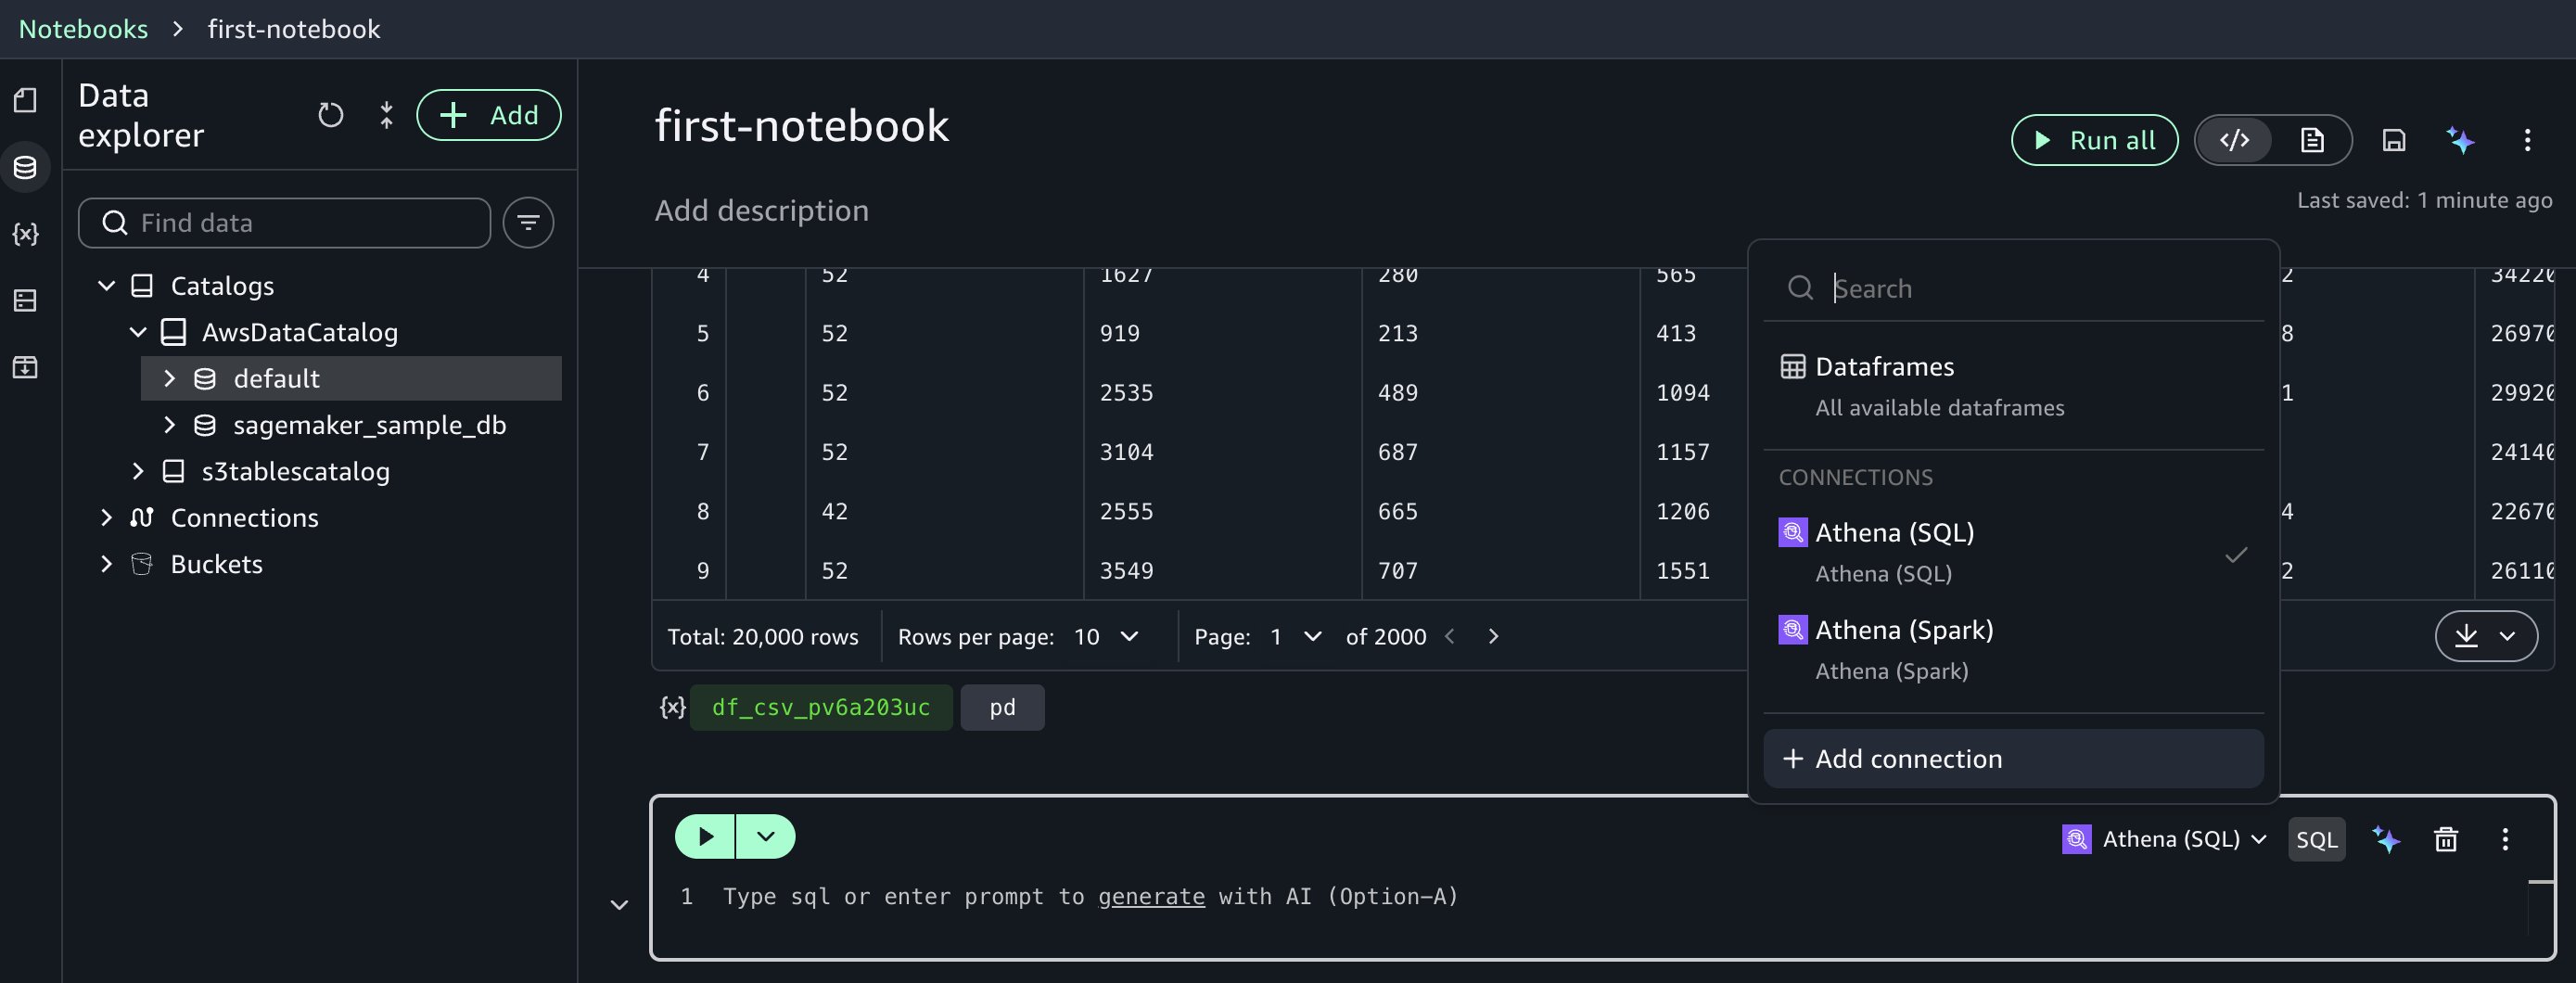
Run this SQL to create a database: create database demo;

Next, go to data explorer and choose +Add on the top left, then choose Create table. Choose the database you created earlier and enter a name for the table. Upload the housing.csv dataset file used earlier. Continue by choosing Next in the side panel to create the table.
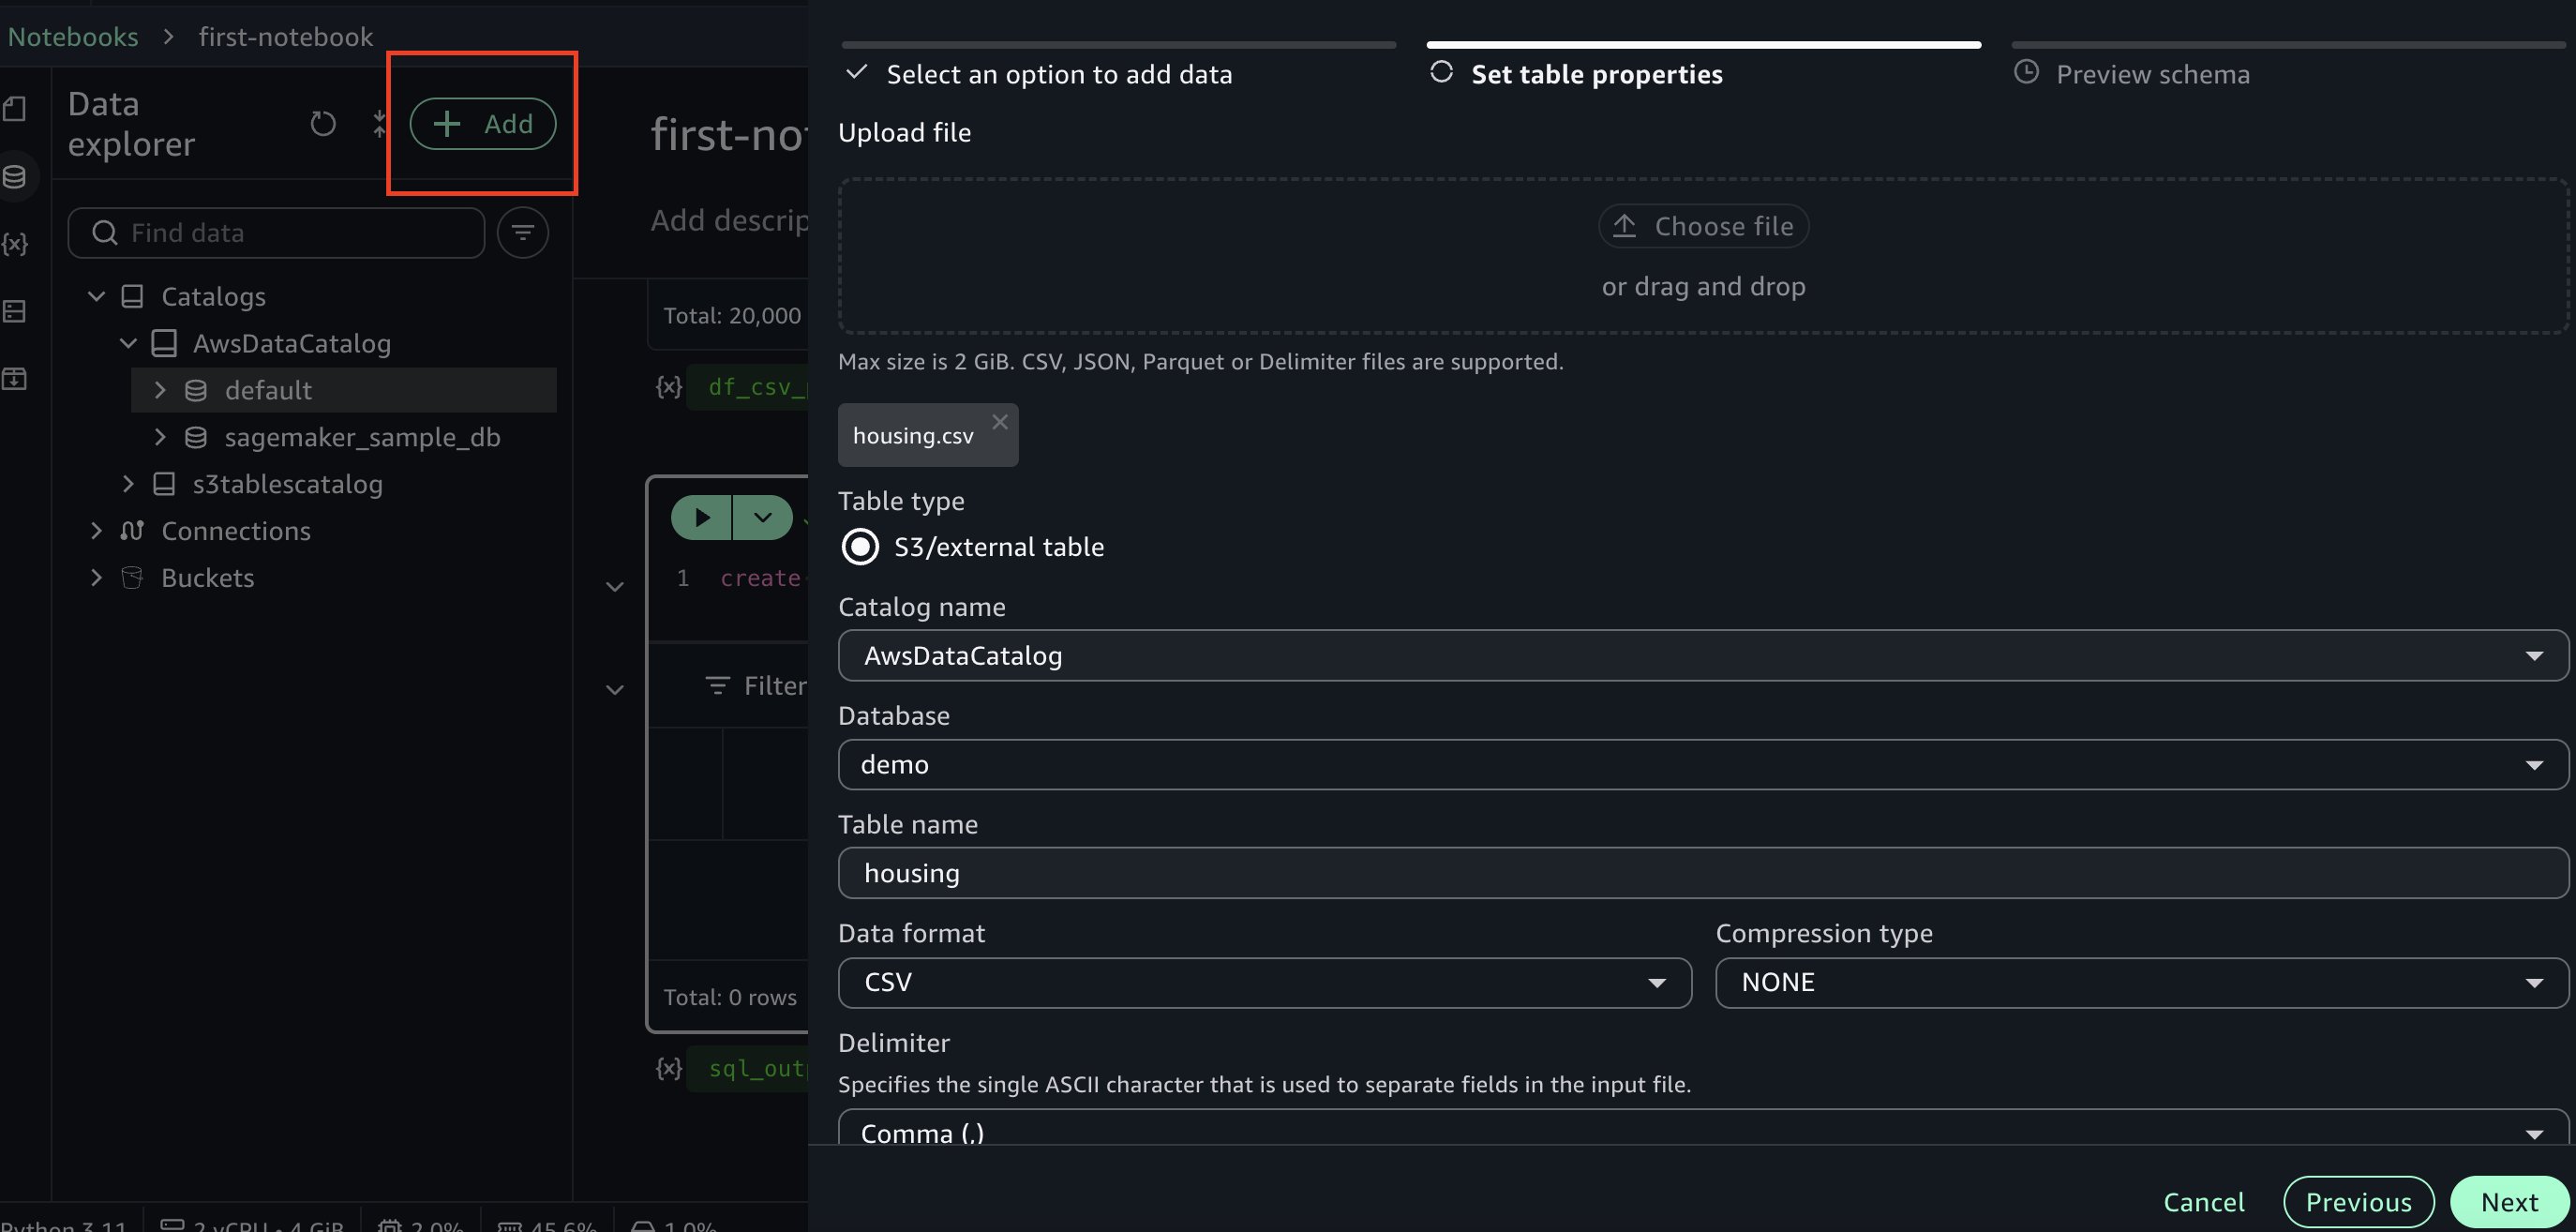
Next, let’s run a sample SQL query in a new cell using Amazon Athena SQL:
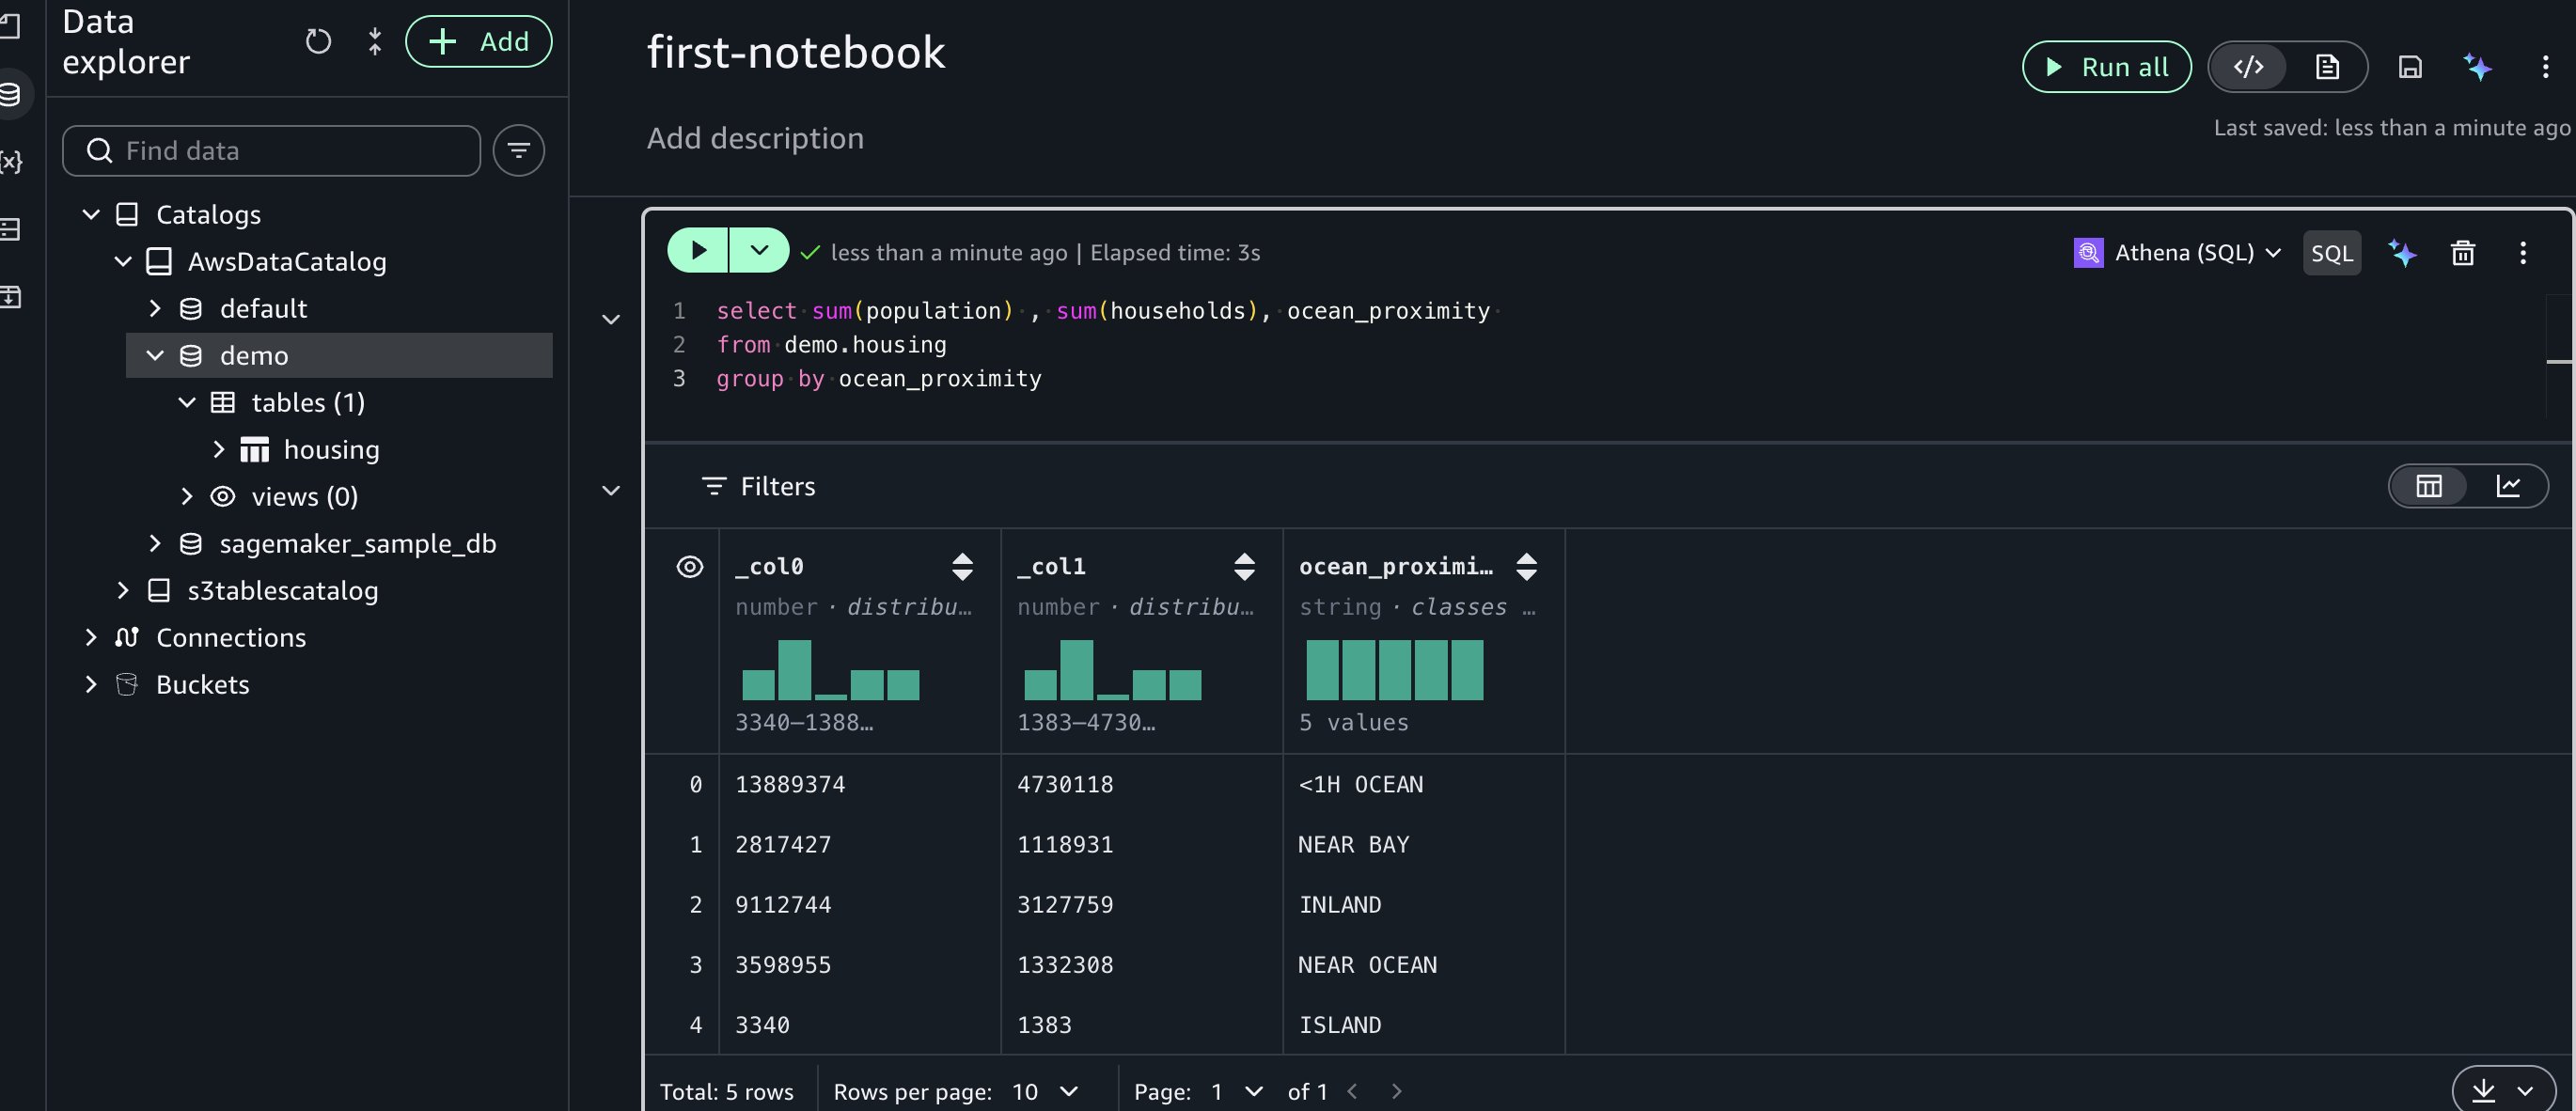
select sum(population) , sum(households), ocean_proximity 
fromdemo.housing
group by ocean_proximity

Advanced capabilities with Athena Spark

Before you can build an ML model to predict house prices, let’s analyze the dataset further and run data profiling for additional insights. For advanced exploration, you can use Amazon Athena Spark within your notebook.To do that, you’ll create a new Python cell which has a built-in Spark session. Run the following code to check the Spark version:
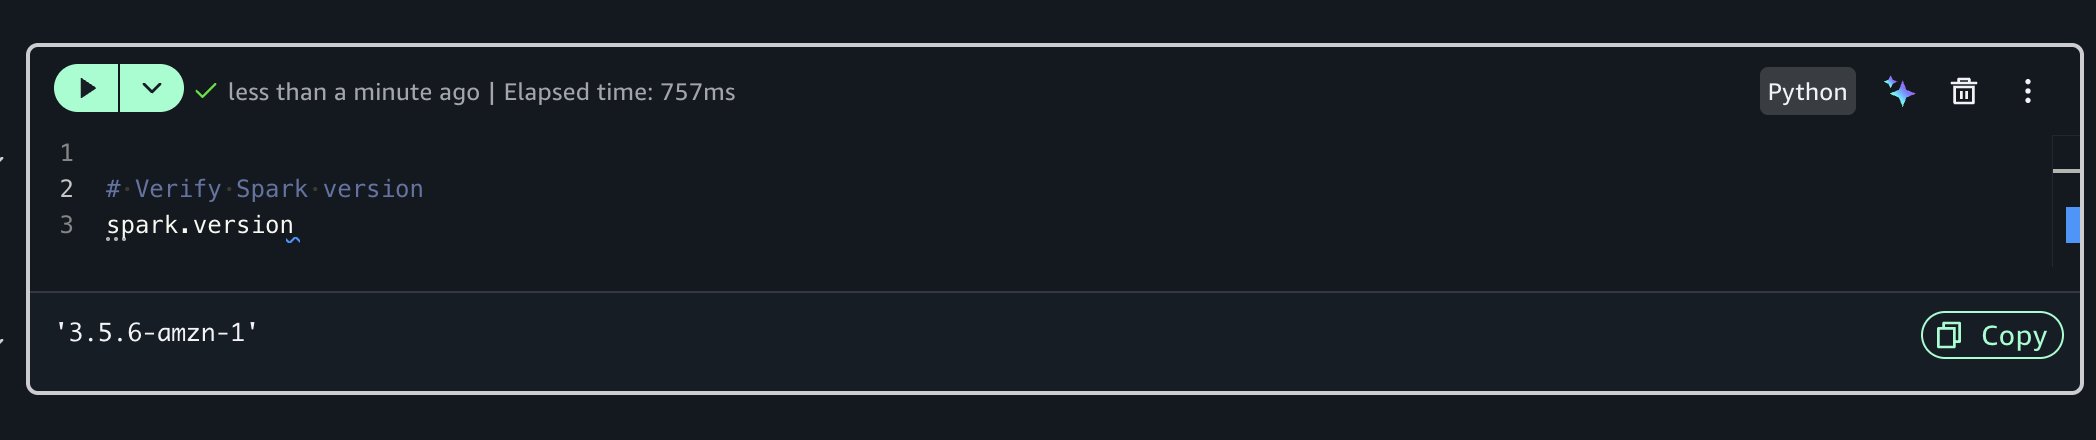
# Verify Spark version
spark.version

Using the SageMaker Data Agent for data profiling

Instead of writing boilerplate code manually, you can use the built-in generative AI capability.

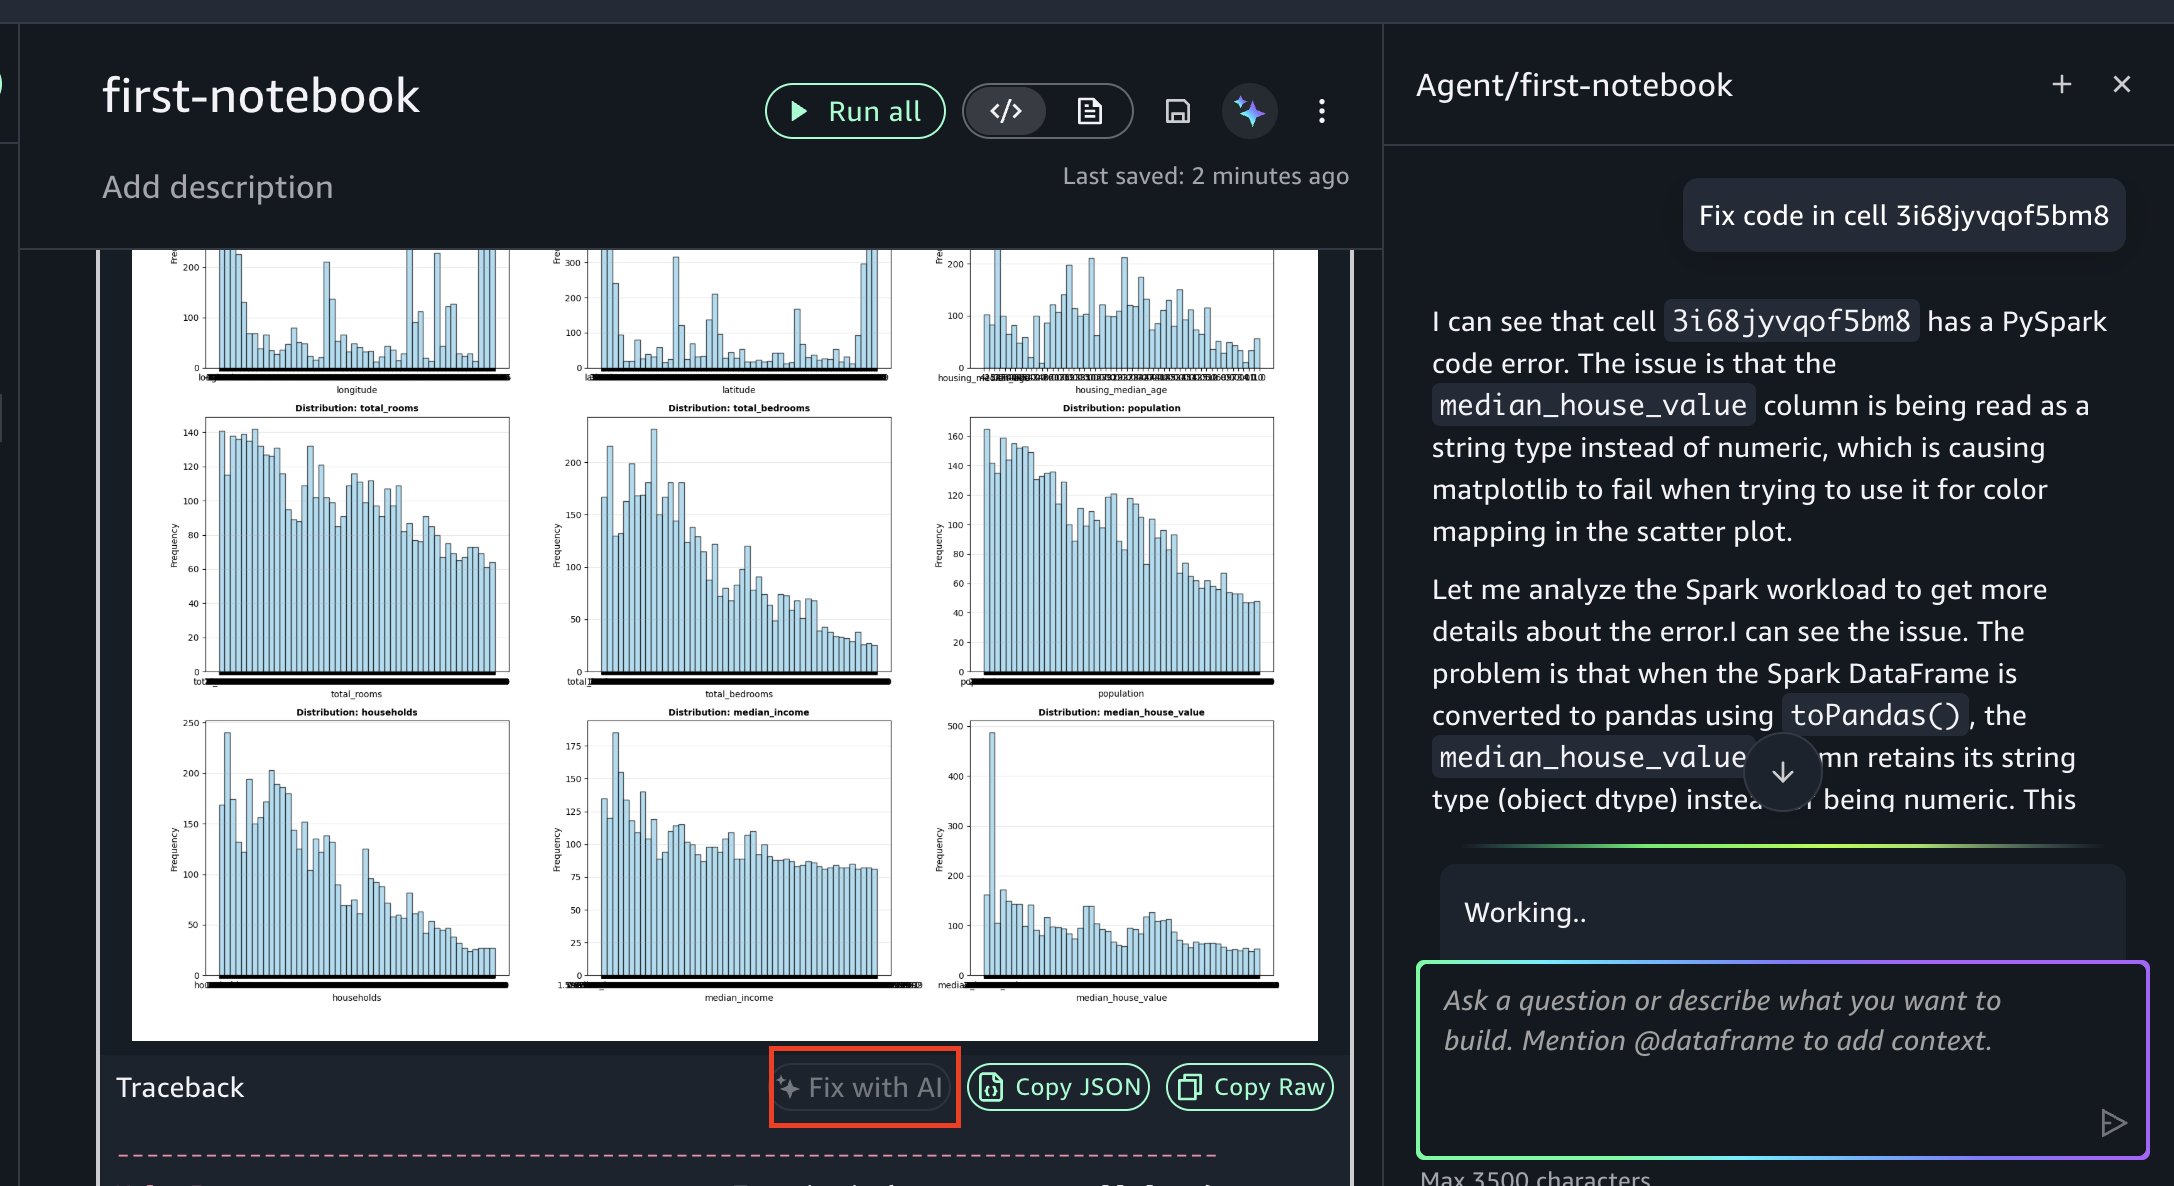
Prompt: “Perform data profiling and create visualization for housing table”

The AI assistant generates comprehensive profiling code for you, including basic statistics calculation, column-level profiling, data type analysis, and missing value detection.
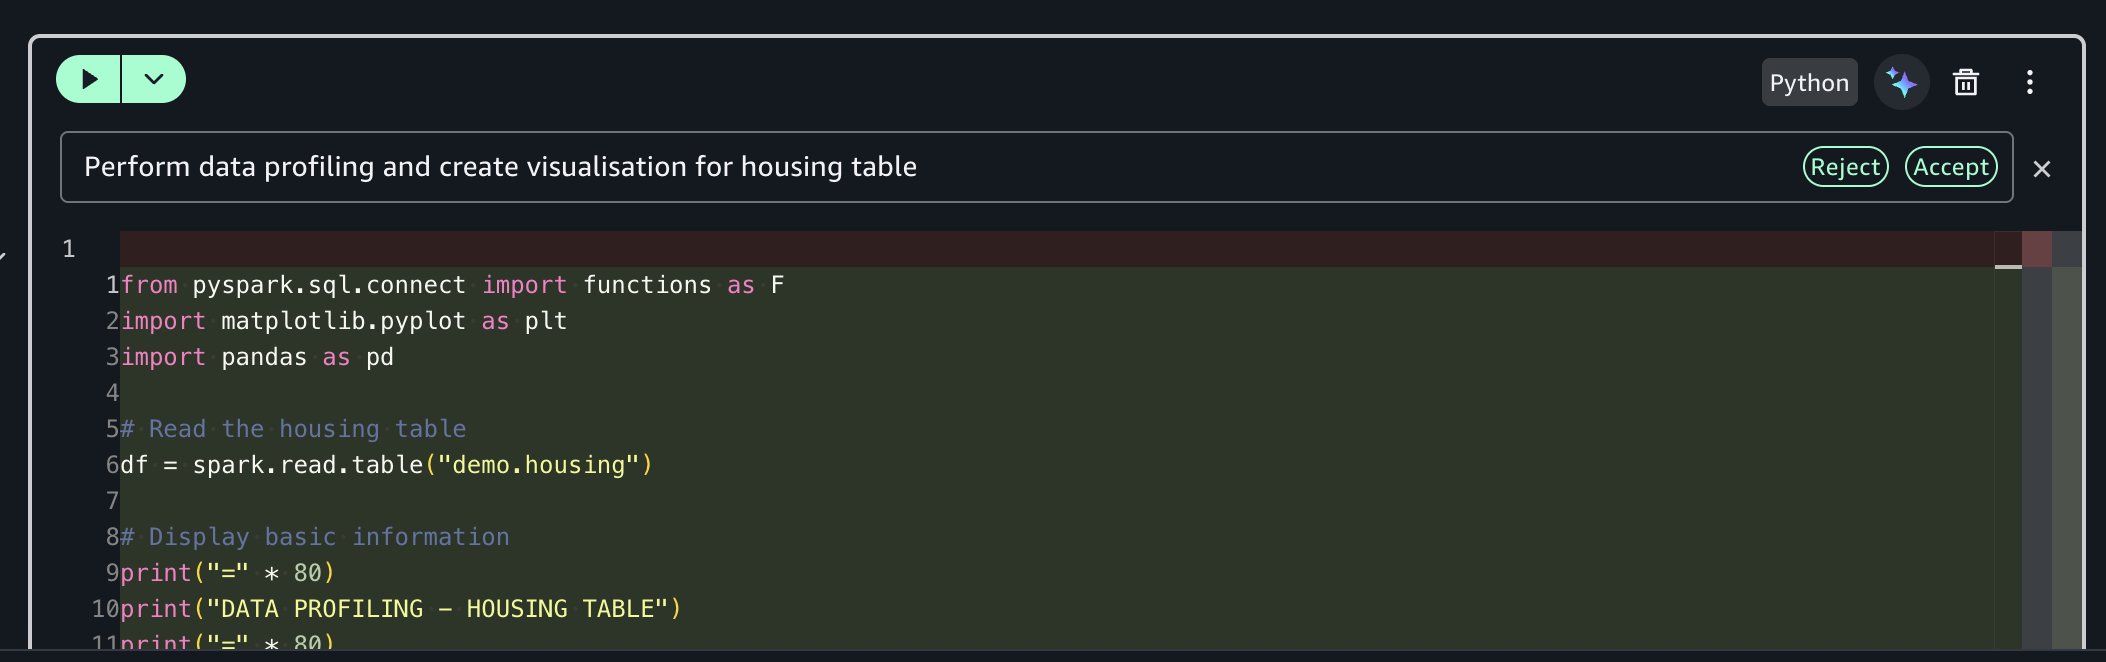
The agent accessed your AWS Glue Data Catalog, understood your housing table structure, and generated profiling code tailored to your specific columns and data types. This context awareness reduces the trial-and-error cycle you’d normally face when adapting generic code snippets to your environment. Review the generated code and run it. The fast response times help you iterate on your analysis efficiently.
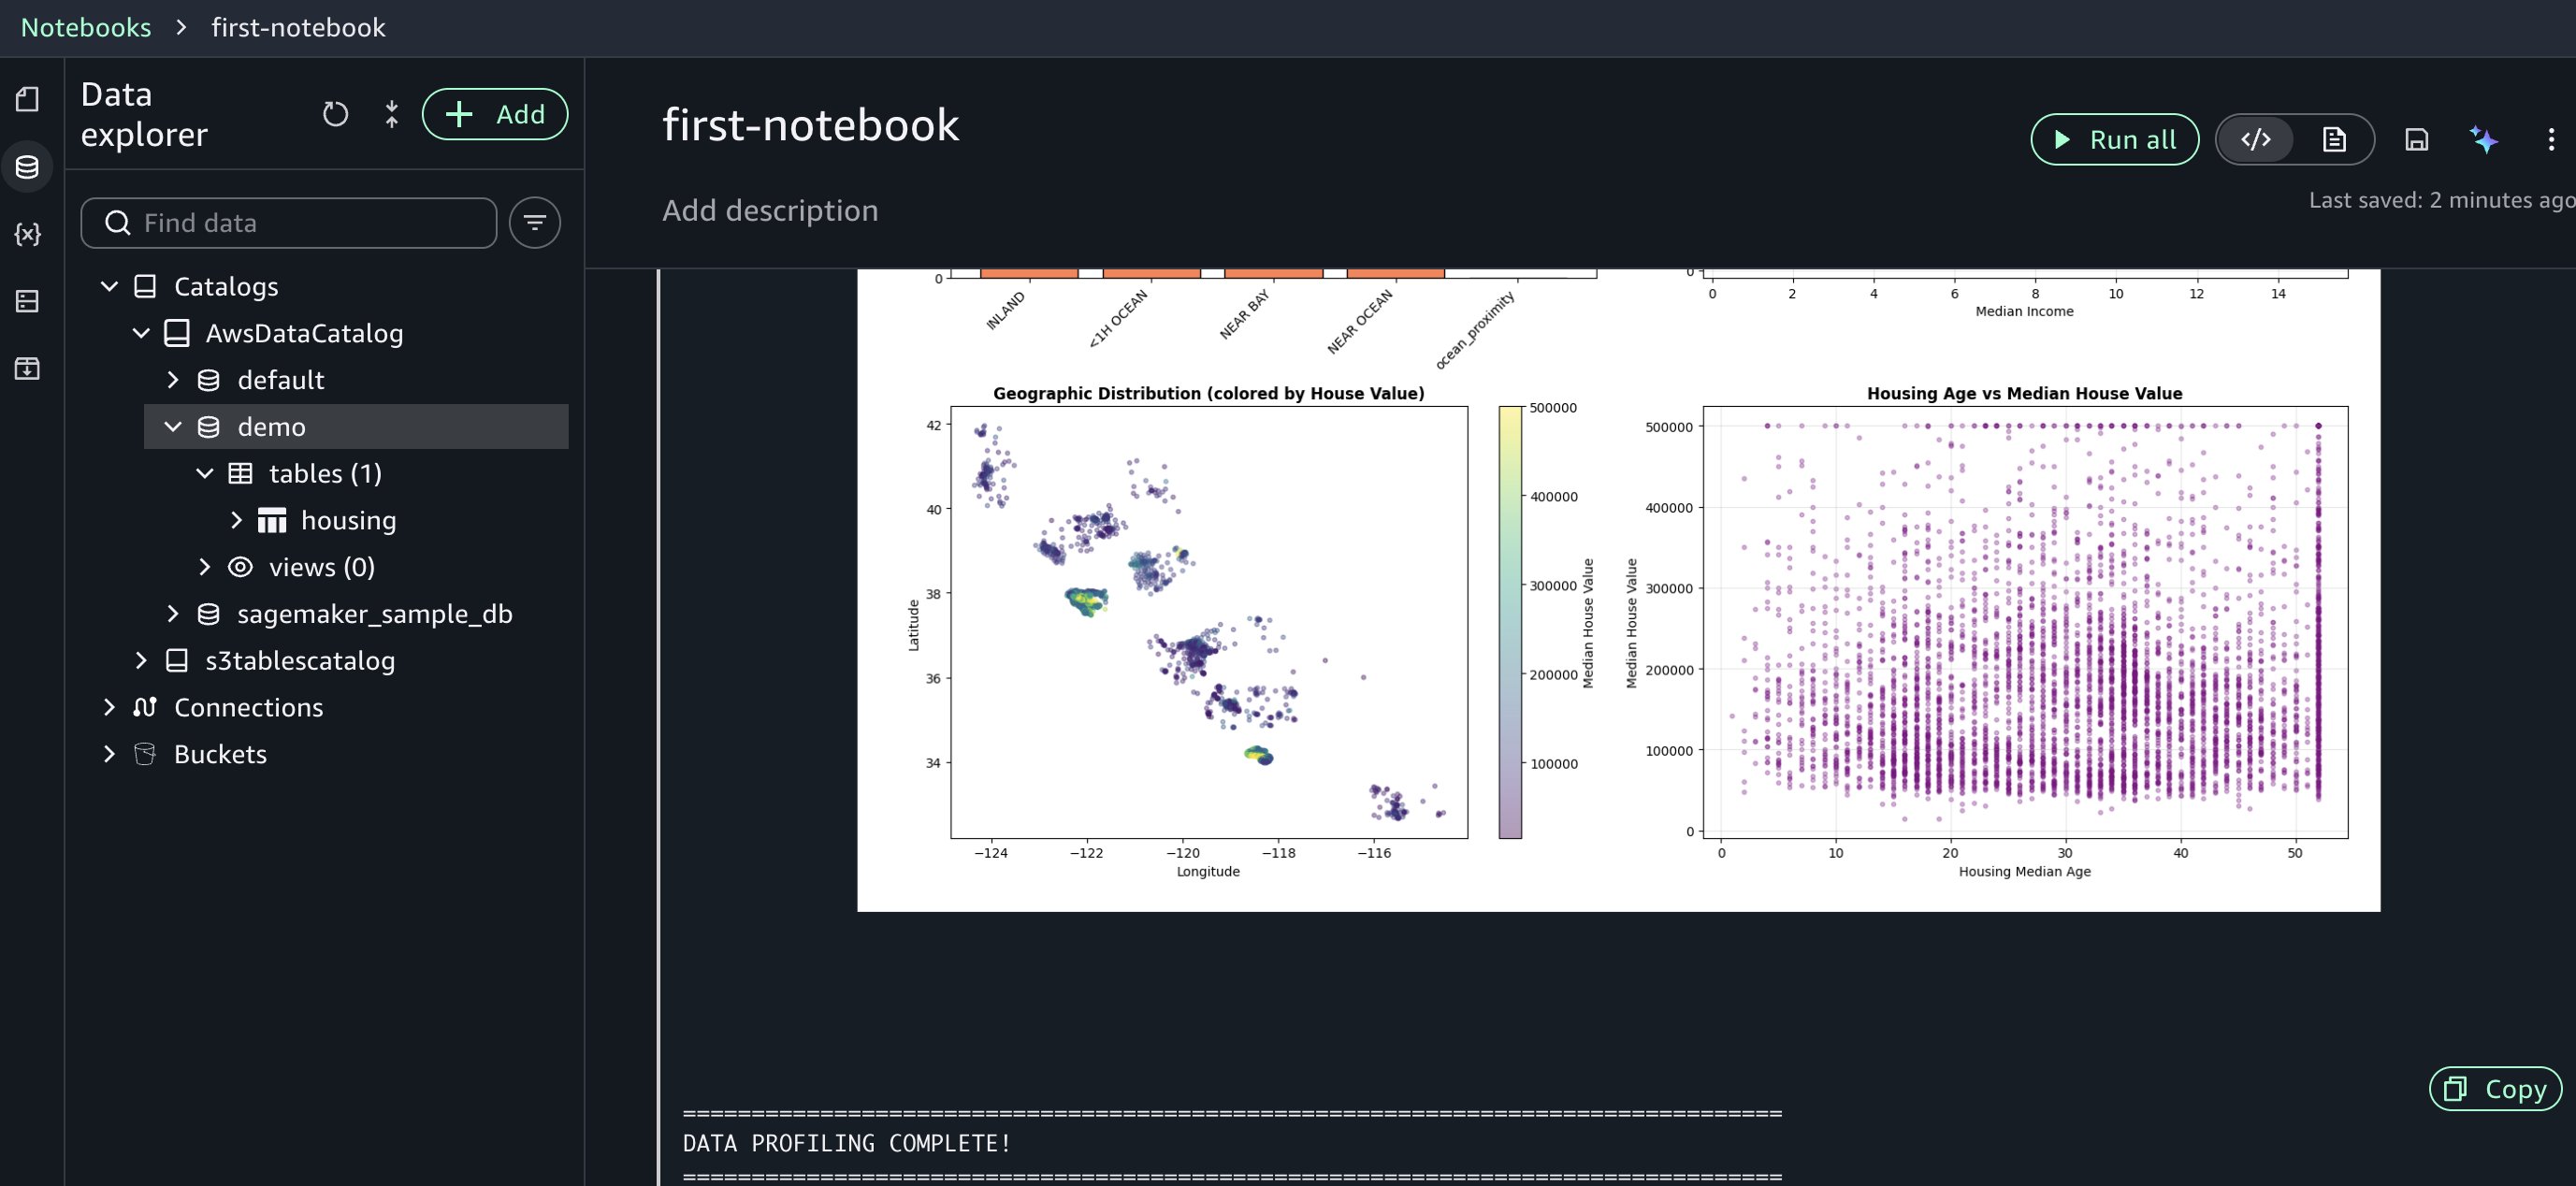
If you encounter an error, you can resolve it using Fix with AI as shown in the following figure. When errors occur during execution, the “Fix with AI” feature analyzes the traceback, diagnoses the root cause, and generates corrected code, so you can keep your analysis moving forward.
Training ML models

Next, you’ll use the data agent to generate code for training a model that predicts housing prices.

Prompt: “Generate code to train a model that predicts housing prices. Use table housing.”
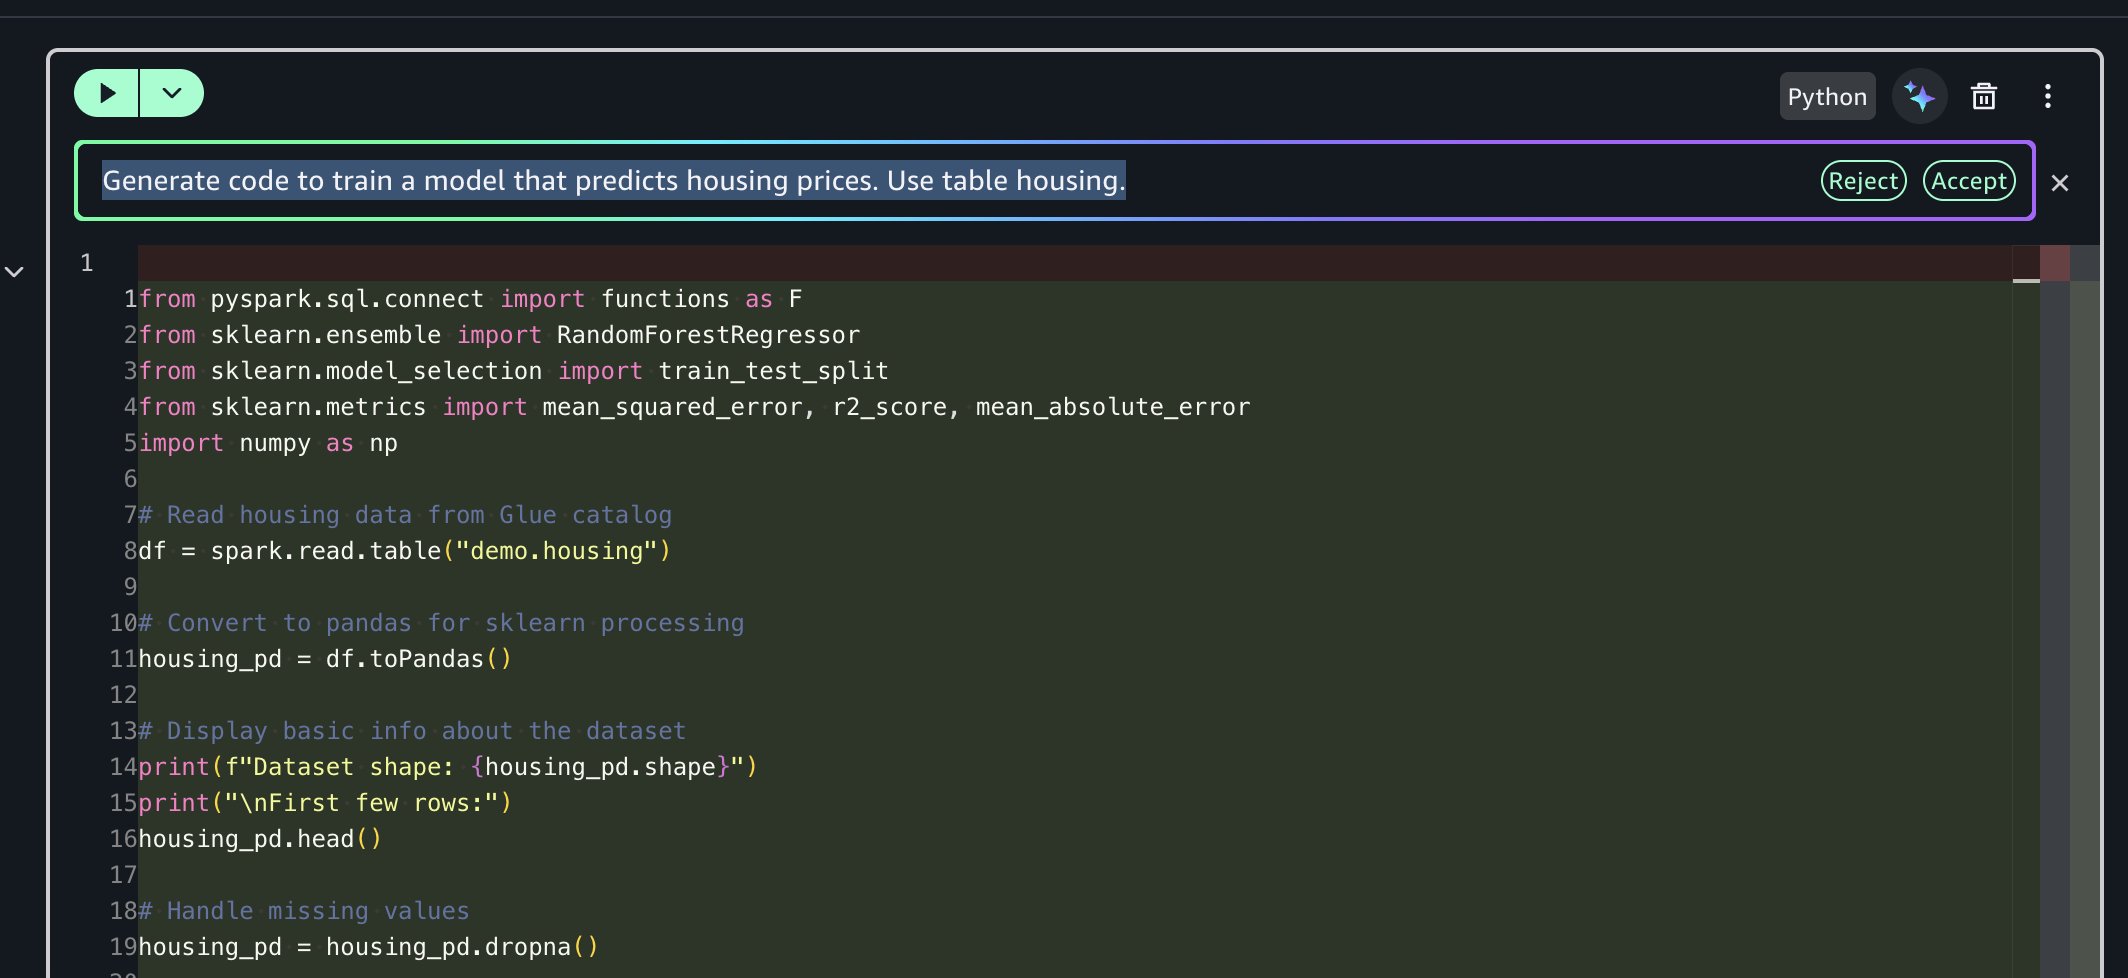
The AI assistant generates end-to-end code for you that:

  1. Reads housing data from AWS Glue catalog using Amazon Athena Spark and converts to pandas
  2. Converts string columns to numeric, encodes using one-hot encoding and removes missing values
  3. Trains a Random Forest model to predict median house values
  4. Evaluates model performance (RMSE, MAE, R-square)
  5. Displays top 10 most important features for predictions

This multi-step orchestration saves you hours of development time by handling the entire workflow from data access to model evaluation.
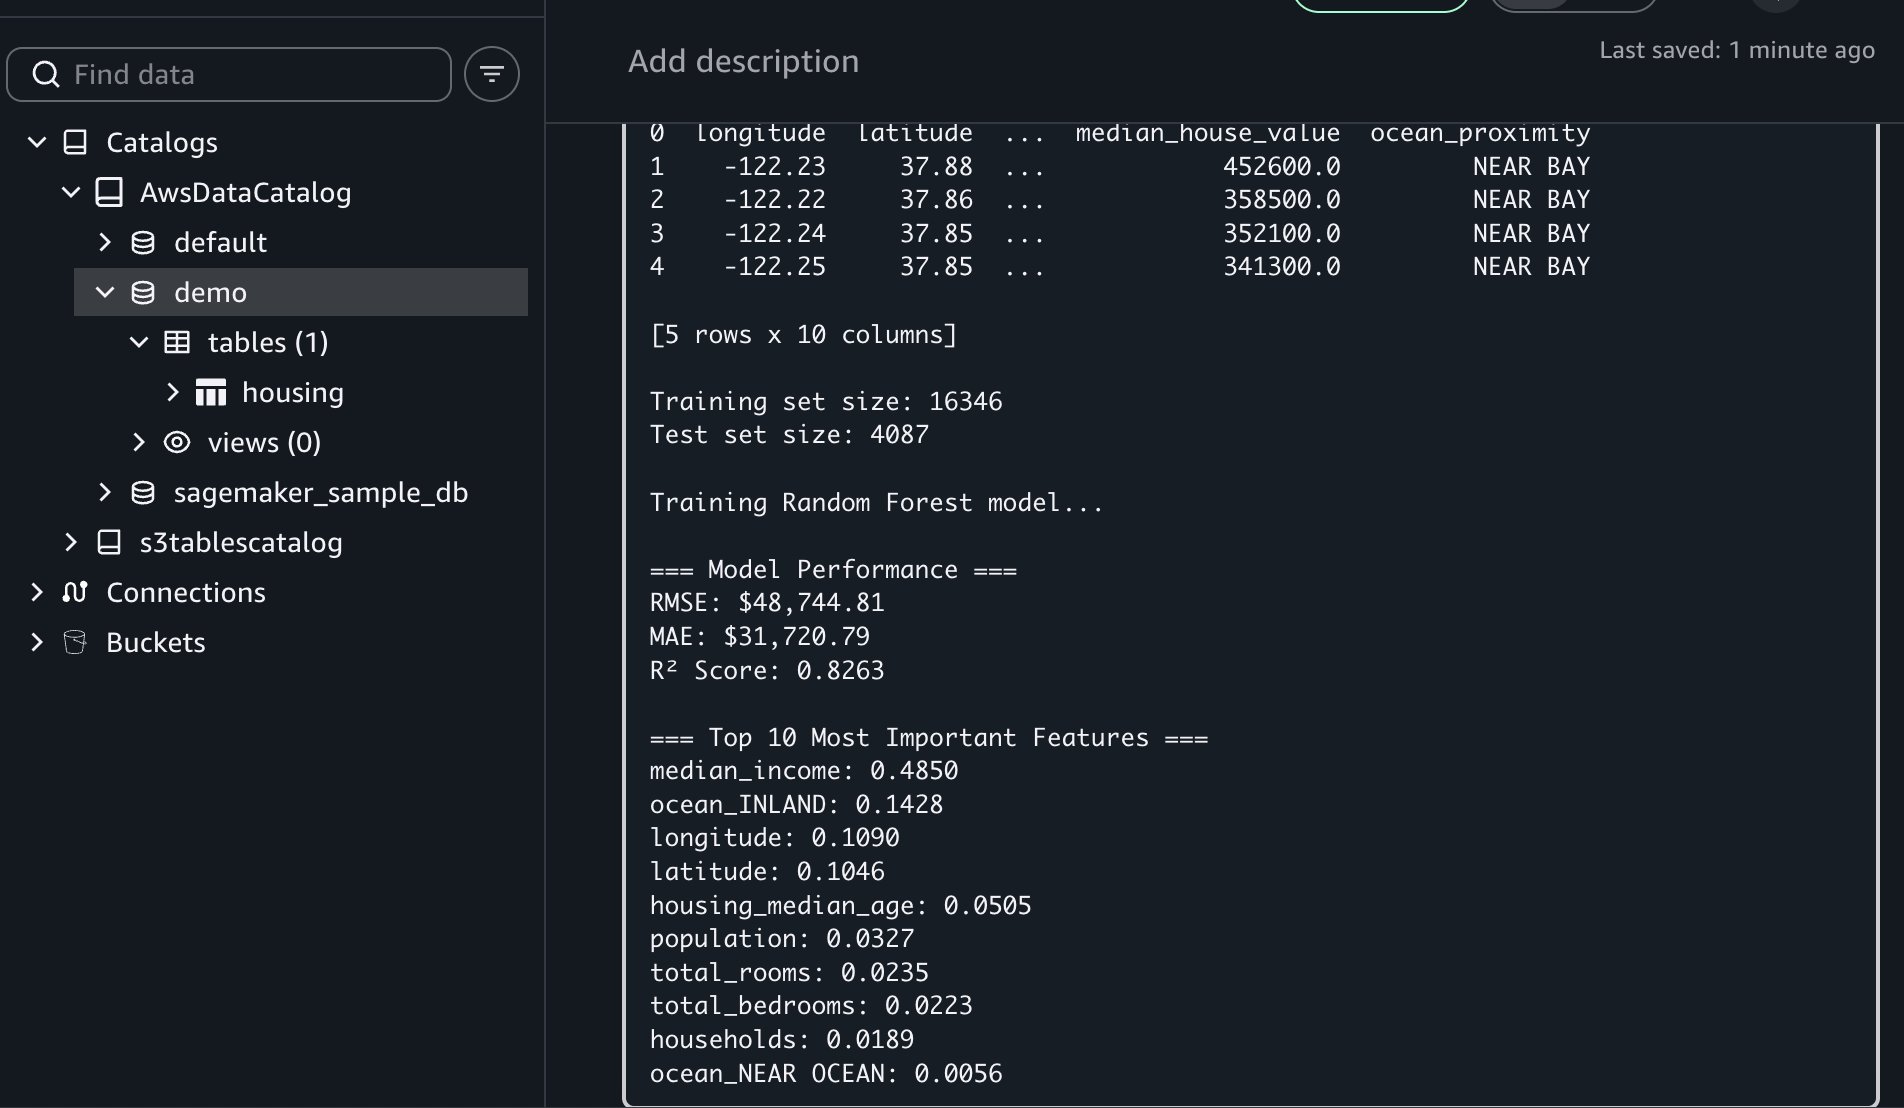
If you encounter an error, you can resolve it using Fix with AI available in the results traceback section.

This workflow showcased Notebooks’ unified capabilities: you uploaded files locally, created AWS Glue tables for multi-engine access, used Amazon Athena Spark for distributed profiling, and used AI-assisted ML development to predict housing prices. All of this happened within a single notebook environment without switching tools.

Key benefits and best practices

Notebooks in Amazon SageMaker Unified Studio deliver several advantages:

  • Faster time to insights: With traditional environments, you might spend hours on configuration before analysis begins. Notebooks bypass this overhead, so you can start work immediately.
  • Improved collaboration: You can share notebooks with consistent environments, supporting reproducibility and reducing “works on my machine” issues.
  • Reduced complexity: You can access multiple data sources and compute engines from one interface rather than navigating separate tools for each data source or processing engine.
  • AI-accelerated development: Generate task-specific code and receive intelligent suggestions, reducing time spent on repetitive coding tasks.
  • Scalable performance: Handle datasets from megabytes to petabytes with appropriate compute resources. The system scales automatically as data volumes grow.

Best practices

  1. Start with appropriate compute profiles by beginning with smaller instances and scaling up as your needs grow.
  2. Use AI assistance with natural language prompts for your repetitive tasks and complex operations.
  3. Combine engines strategically by using Amazon Athena Spark for your large-scale processing, Amazon Redshift for data warehousing and other specialized engines for your specific workloads.
  4. Document your work using markdown cells to create living documentation alongside your code.
  5. Organize using multiple cells by breaking the complex workflows into logical steps for better readability and debugging.

Cleaning up

To avoid incurring future charges, delete the resources you created in this walkthrough:

  1. In the Amazon SageMaker Unified Studio console, navigate to the Notebook page
  2. Delete the notebook
  3. Delete the demo database and housing table from the AWS Glue Data Catalog
  4. Delete Amazon SageMaker Unified Studio domain created during this walkthrough
  5. If you created a new IAM role specifically for this walkthrough, delete it from the IAM console

Conclusion

In this post, we demonstrated how Notebooks in Amazon SageMaker Unified Studio help you work more efficiently and deliver insights more quickly. By combining familiar notebook interfaces with enterprise-scale compute, multi-engine support, and generative AI assistance, teams can streamline data and AI workflows.

The integration of Python and SQL, instant access to diverse data sources, and intelligent code generation capabilities make Notebooks a valuable tool for modern data teams. Teams can perform exploratory data analysis, build complex data pipelines, or train ML models with the flexibility and power needed within a single, intuitive environment.

Ready to get started? Create your first notebook in Amazon SageMaker Unified Studio and begin analyzing data within minutes.

Explore additional capabilities:

  • Time series analysis workflows with seasonal decomposition and forecasting
  • Natural language processing pipelines for text classification and sentiment analysis
  • Integration with Amazon SageMaker Model Registry for ML model versioning
  • Advanced Spark optimization techniques for petabyte-scale processing

Learn more:


About the authors

Praveen Kumar

Praveen Kumar is a Principal Analytics Solutions Architect at AWS with expertise in designing, building, and implementing modern data and analytics applications using cloud-based services. His areas of interest are serverless technology, data governance, and data-driven AI applications.

Majisha Namath Parambath

Majisha Namath Parambath is a Principal Engineer at Amazon SageMaker, bringing over a decade of experience at AWS to her role. She spearheads critical initiatives for Amazon SageMaker Unified Studio, the next-generation service that provides comprehensive data analytics and interactive machine learning capabilities with an emphasis on agentic systems. Her expertise encompasses system design, architecture, and cross-functional execution, with particular attention to security, performance, and reliability at enterprise scale. When she’s not engineering solutions, Majisha enjoys reading, cooking, and hitting the slopes for skiing.

Siddharth Gupta

Siddharth Gupta is heading Generative AI within SageMaker’s Unified Experiences. His focus is on driving agentic experiences, where AI systems act autonomously on behalf of users to accomplish complex tasks. Previously, he led edge machine learning solutions at AWS. His work focuses on improving how developers and data scientists interact with AI, creating more intuitive data integrations and better tools for building and deploying machine learning models. An alumnus of the University of Illinois at Urbana-Champaign, he brings extensive experience from his roles at Yahoo, Glassdoor, and Twitch. You can reach out to him on LinkedIn.

Using Amazon SageMaker Unified Studio Identity center (IDC) and IAM-based domains together

Post Syndicated from Praveen Kumar original https://aws.amazon.com/blogs/big-data/using-amazon-sagemaker-unified-studio-identity-center-idc-and-iam-based-domains-together/

Amazon SageMaker Unified Studio now offers two domain configurations: Amazon SageMaker Unified Studio Identity Center(IDC)-based domains with comprehensive governance features, and Amazon SageMaker Unified Studio IAM-based domains with enhanced developer productivity tools.

In this post, we demonstrate how you can use both of these domain configurations of Amazon SageMaker Unified Studio using AWS Identity and Access Management (IAM) role reuse and attribute-based access control.

How authentication works in each configuration

Amazon SageMaker Unified Studio IDC-based domains authenticate users through AWS Identity and Access Management (IAM) Identity Center with Single Sign-On, preserving individual user identities throughout their sessions. These domains excel in governance with identity-based authorization, fine-grained access controls between users, and comprehensive catalog management featuring formal Publisher/Subscriber (Pub/Sub) data sharing workflows with approval processes—ideal for enterprise environments requiring strong identity management, compliance tracking, and identity-based audit trails.

Amazon SageMaker Unified Studio IAM-based domains authenticate through federated AWS Identity and Access Management (IAM) roles where all users accessing a project share the same role permissions. These domains prioritize developer productivity with modern tools including new serverless Notebooks, Athena Spark integration, the improved interface with vertical navigation, and built-in AI assistance, designed for development teams that need streamlined access and advanced analytics capabilities.

This solution facilitates organizations that are already using IDC-based domains to preserve their existing governance frameworks established in IDC-based domains while unlocking modern development capabilities for their teams through IAM-based domains. If you prefer to use the newly launched IAM-based domains, you can continue to do as well. The choice depends on your company’s needs.

Please note that at the time of writing this blog, IAM-based domains do not support Trusted identity propagation. This solution uses the project execution role to configure data access.

The challenge

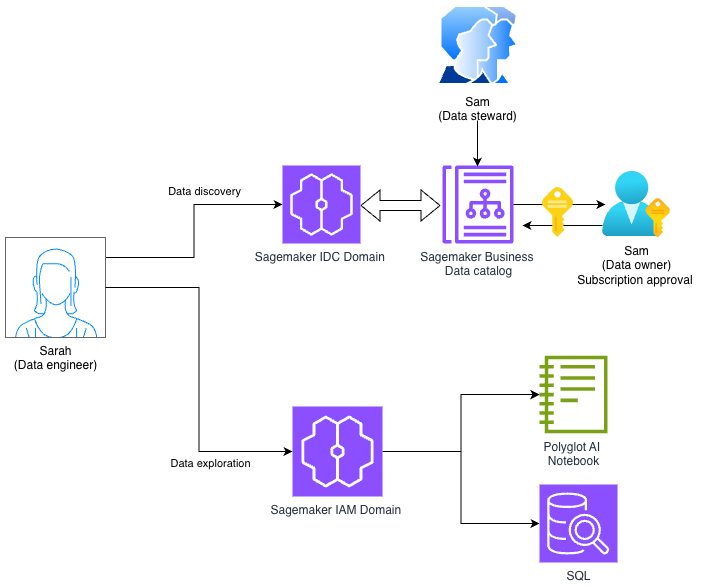
Imagine a data steward (Sam) uses the IDC-based domain to define data access policies, manage the data catalog, and approve subscription requests to verify compliance and proper data governance.

On the other hand, a data engineer (Sarah), wants to use IDC-based domain for governance features such as SageMaker catalog and IAM-based domain for the new serverless Notebook to build data pipelines, perform advanced analytics, and accelerate development cycles. Sarah will request access to the data through IDC-based domain, and once access is approved by Sam, Sarah can access this data in serverless notebook available in IAM-based domain.

Solution overview

The integration leverages IAM role reuse, AWS Lake Formation Attribute-Based Access Control (ABAC) and Amazon SageMaker Catalog pub-sub model to automatically carry permissions from the IDC-based domain to the new IAM-based domain. When properly configured, data subscriptions managed through the IDC-based domain’s Pub/Sub model become immediately accessible in IAM-based domain projects, providing a unified data access experience.

The solution we will implement in the post involves creating an IAM-based domain project that is similar to your IDC consumer project (eg same team members, use case) , configuring execution roles, and enabling role reuse. This approach maintains the familiar subscription workflow while extending benefits to the IAM-based domain.The following diagram shows the high-level architecture of how this approach works.

AWS SageMaker data governance workflow diagram showing data engineer Sarah performing data discovery and exploration through SageMaker IDC and IAM domains, with data steward and owner Sam managing approvals via Business Data Catalog, connecting to Polyglot AI Notebook and SQL tools.

The solution architecture consists of:

  • Existing IDC-based domain: Contains producer and consumer projects with established data sharing via Pub/Sub model
  • IAM-based domain: New projects with federated and execution roles configured for modern development tools
  • IAM Identity Center: Manages federated access and permission sets
  • Attribute-Based Access Control: Tags on execution roles enable automatic permission inheritance

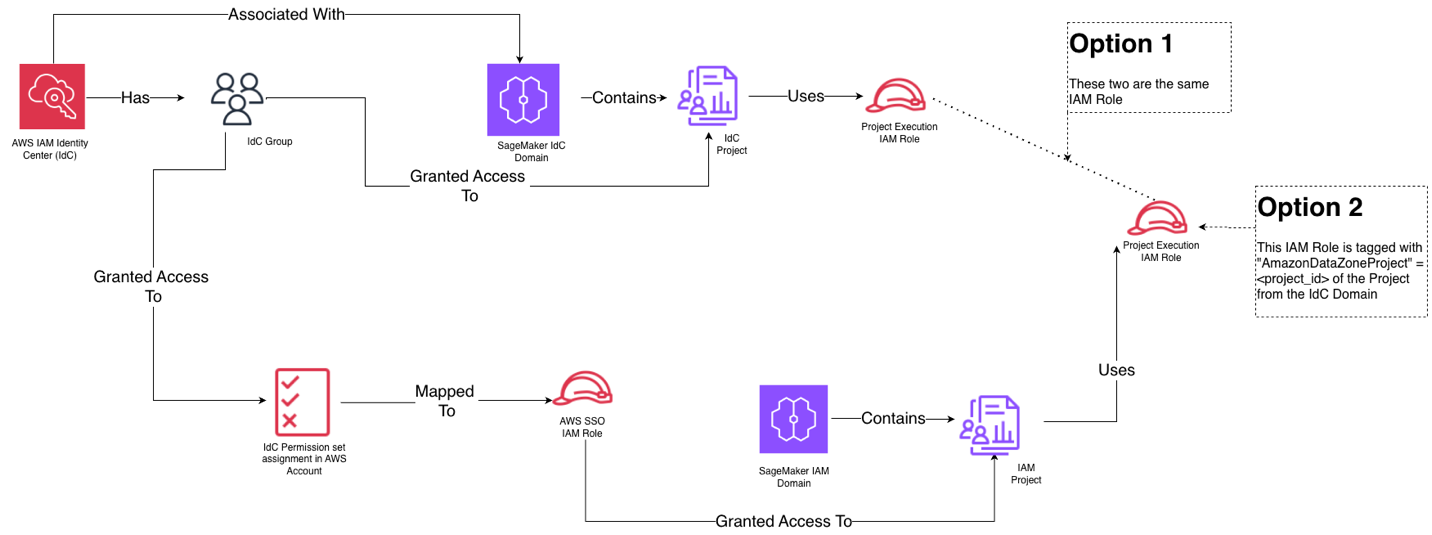
The solution provides 2 options: Option 1: IDC-Based Domain project role reuse provides the simplest integration path by directly reusing the existing consumer project IAM role from your IDC-based domain as the execution role in the IAM-based domain. The primary benefits include simplified setup requiring only policy changes (covered later in the blog), reduced administrative overhead with one less role to manage and lower risk of misconfiguration since you’re leveraging proven, existing roles. Choose Option 1 when you want the fastest implementation path, your organization prefers minimal role proliferation, you have well-established IDC-based domain roles that already have data access permissions, or your team has limited IAM expertise and wants to avoid complex tagging configurations.

Option 2: Creating a new execution role for the IAM-based domain project and use attribute-based access control (ABAC) through tagging with the IDC-based domain project ID. The key benefits include enhanced auditability with two distinct roles (one for IDC-based domain, one for IAM-based domain), clear separation showing which domain generated each request in CloudTrail logs, greater flexibility to customize permissions specific to IAM-based domain needs without affecting IDC-based domain operations, and better security isolation between the two domain types. The `AmazonDatazoneProject` tag enables attribute based access control, while maintaining distinct role identities. Choose Option 2 when: your organization requires detailed audit trails distinguishing between domain types, compliance policies mandate separation of concerns between governance and development environments, you want to track and attribute costs separately for each domain, or you need to provide evidence showing which domain (governance vs. development) accessed specific data resources for compliance reporting.

Here is the high-level view of how the identity and domain entities map to each other for both options:

AWS IAM Identity Center integration with Amazon SageMaker diagram showing access flow from IdC Groups through Permission Sets to AWS SSO IAM Roles, connecting to SageMaker domains with two implementation options: Option 1 using identical IAM roles, or Option 2 using project-tagged execution roles

Prerequisites

To follow along with this post, you should have:

For this demonstration, we use a simplified setup with a sales producer project and a marketing consumer project that subscribes to these tables.

Understanding the current IDC-based domain setup

Our starting point includes a well-established Amazon SageMaker Unified Studio IDC-based domain structure:

Sales Producer Project

  • Contains a database with pipeline and sales tables
  • Managed by Sam, the data steward who creates and publishes data assets
  • Has its own project IAM role

Marketing Consumer Project

  • Managed by Sarah, the data engineer who subscribes to published data via IDC domain project
  • Has its own project IAM role
  • Successfully queries subscribed data through the IDC-based domain interface

Each project has an associated IAM role that governs access to data assets, and the Pub/Sub model manages subscription workflows and permissions.

Setting up federated role through permission sets

Federated roles through permission sets are used to authenticate and provide users with console access to IAM-based domains through AWS IAM Identity Center, where all users within a project share the same role permissions. When you assign a permission set, IAM Identity Center creates corresponding IAM Identity Center-controlled IAM role in AWS account, and attaches the policies specified in the permission set to that role.

IAM-based SMUS domains enable streamlined access to modern development tools (serverless Notebooks, Athena Spark, AI assistance) while maintaining governance, automatically propagating permissions across domains without requiring duplicate access approvals, and simplifying team member onboarding.You can use any IAM role to access IAM-based domain. For this post, we will use federated role option using AWS IAM Identity Center (IDC).

Grant access to Data engineer group for IAM-based domains in Identity Center

1) Set up federated role in AWS IAM Identity Center

Navigate to IAM Identity Center (IDC) in the AWS Management Console, then complete the following steps:

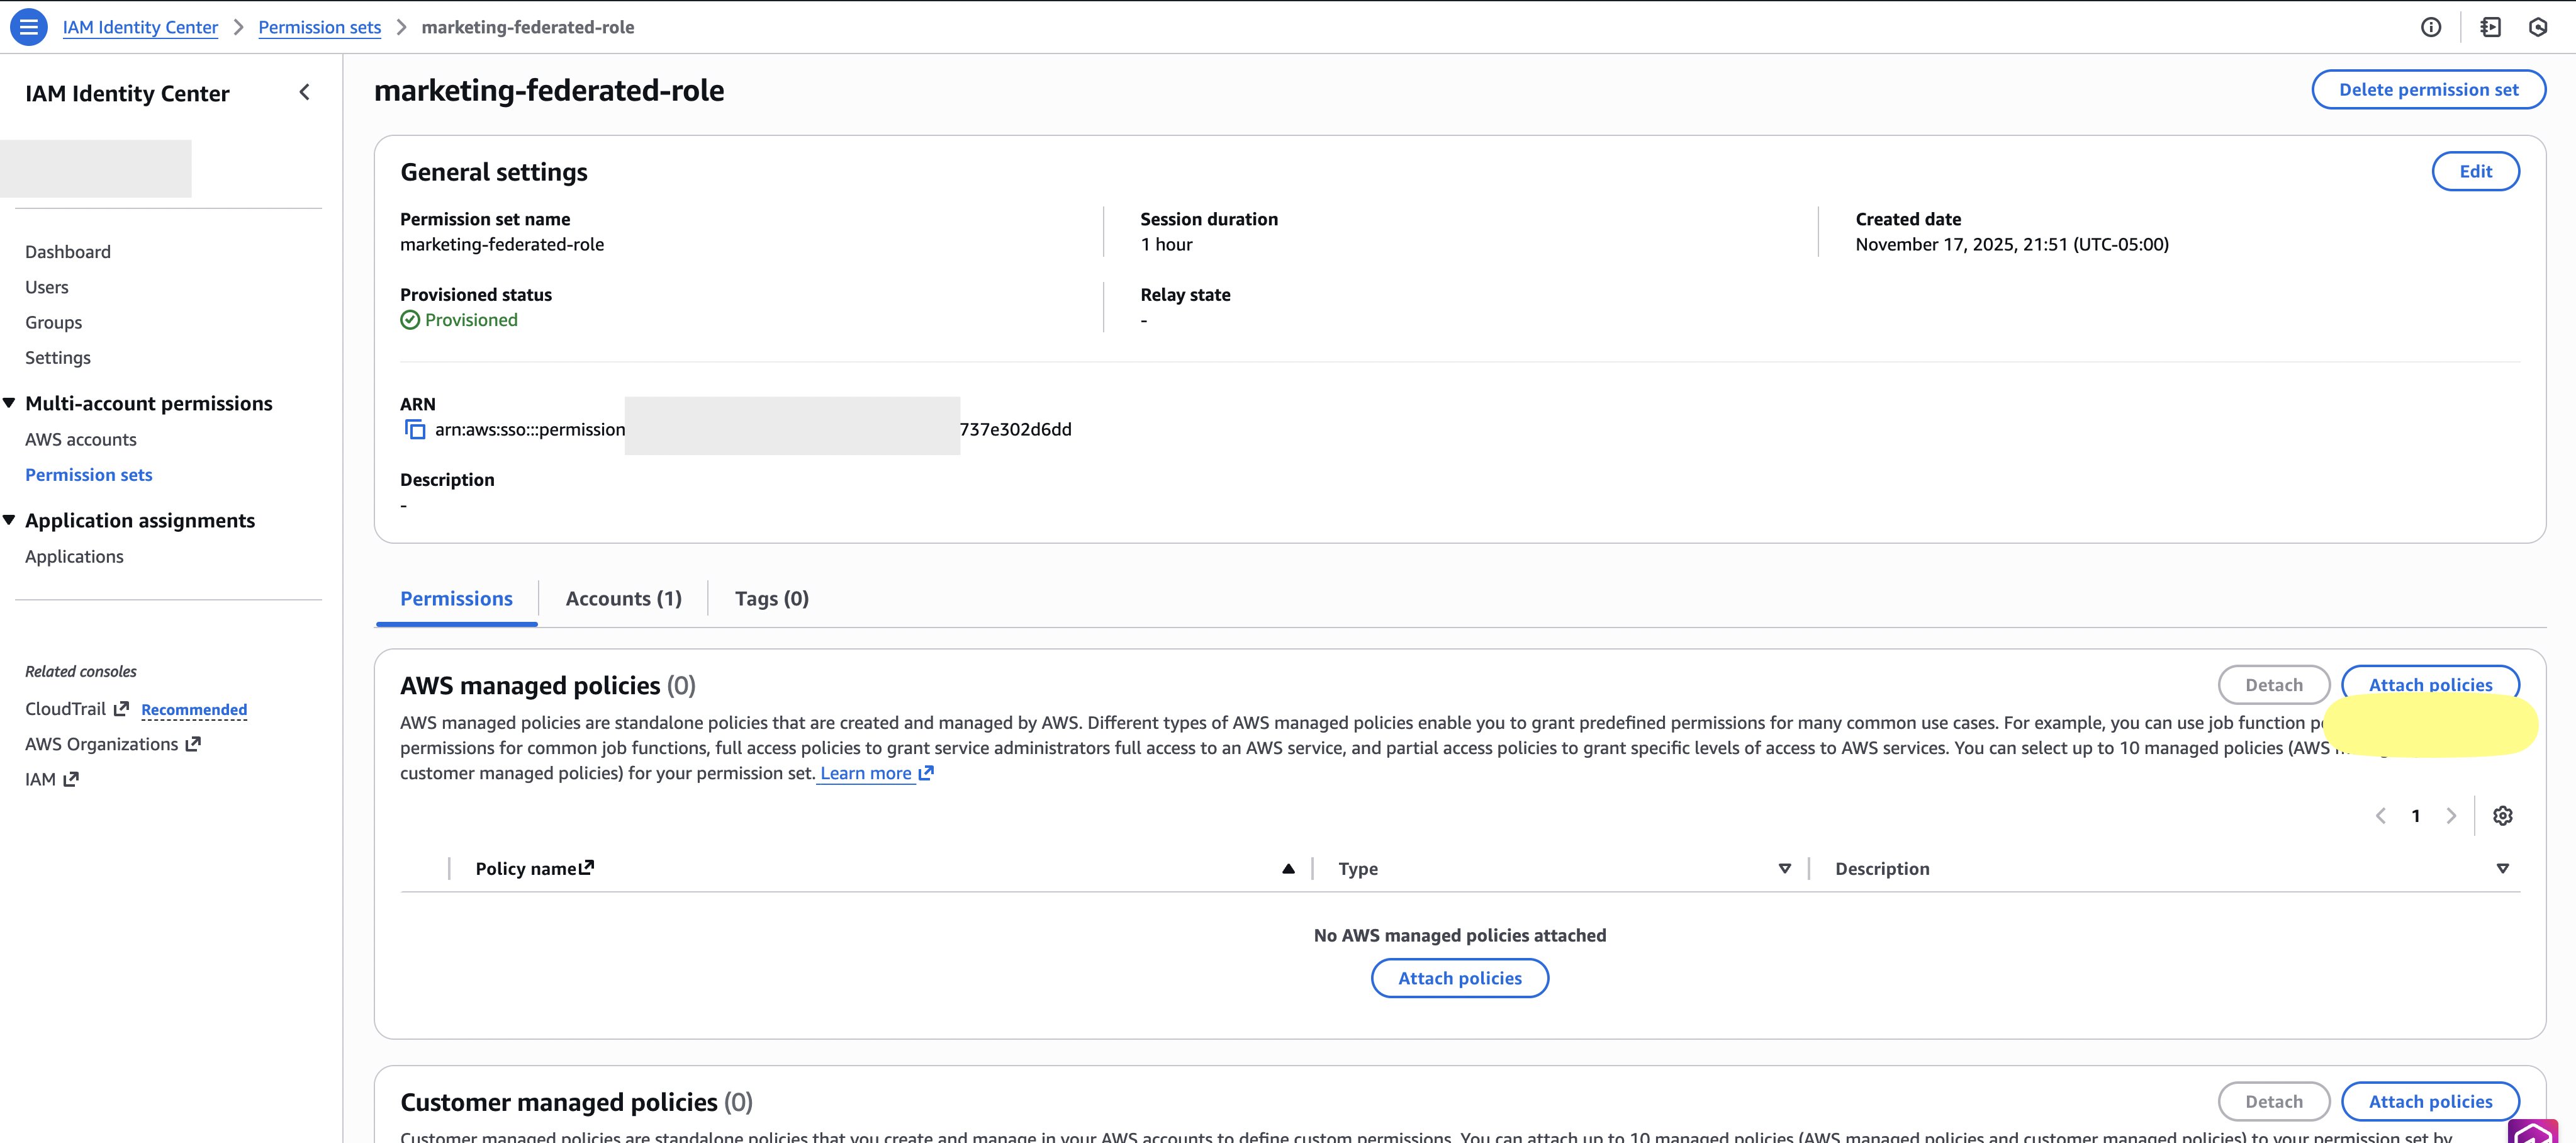
  1. Go to permission set section in IDC. Create a new permission set called Marketing-federated-role and select Attach Policy.

AWS IAM Identity Center console screenshot displaying the marketing-federated-role permission set configuration page with provisioned status, 1-hour session duration, and empty AWS managed and customer managed policy sections with attach policy options.

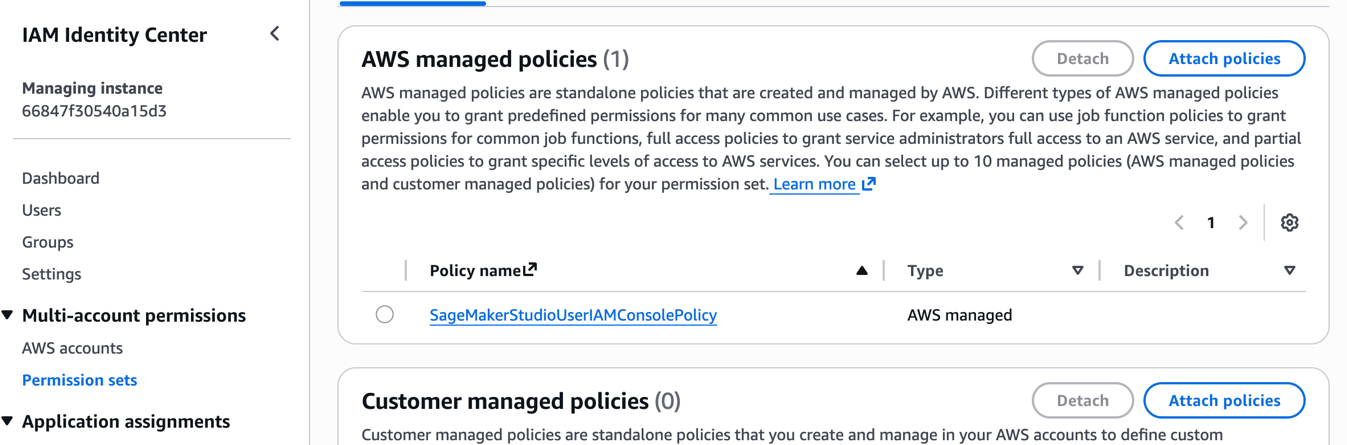
  1. Search for SageMakerStudioUserIAMConsolePolicy in the existing policy name from list and select SageMakerStudioUserIAMConsolePolicy from the list. Note that the managed policy SageMakerStudioUserIAMConsolePolicy must be attached or have the same permissions added via another policy to be able to access projects in a SageMaker IAM domain.

AWS IAM Identity Center console screenshot showing AWS managed policies section with one attached SageMakerStudioUserIAMConsolePolicy and empty customer managed policies section with detach and attach policy options available.

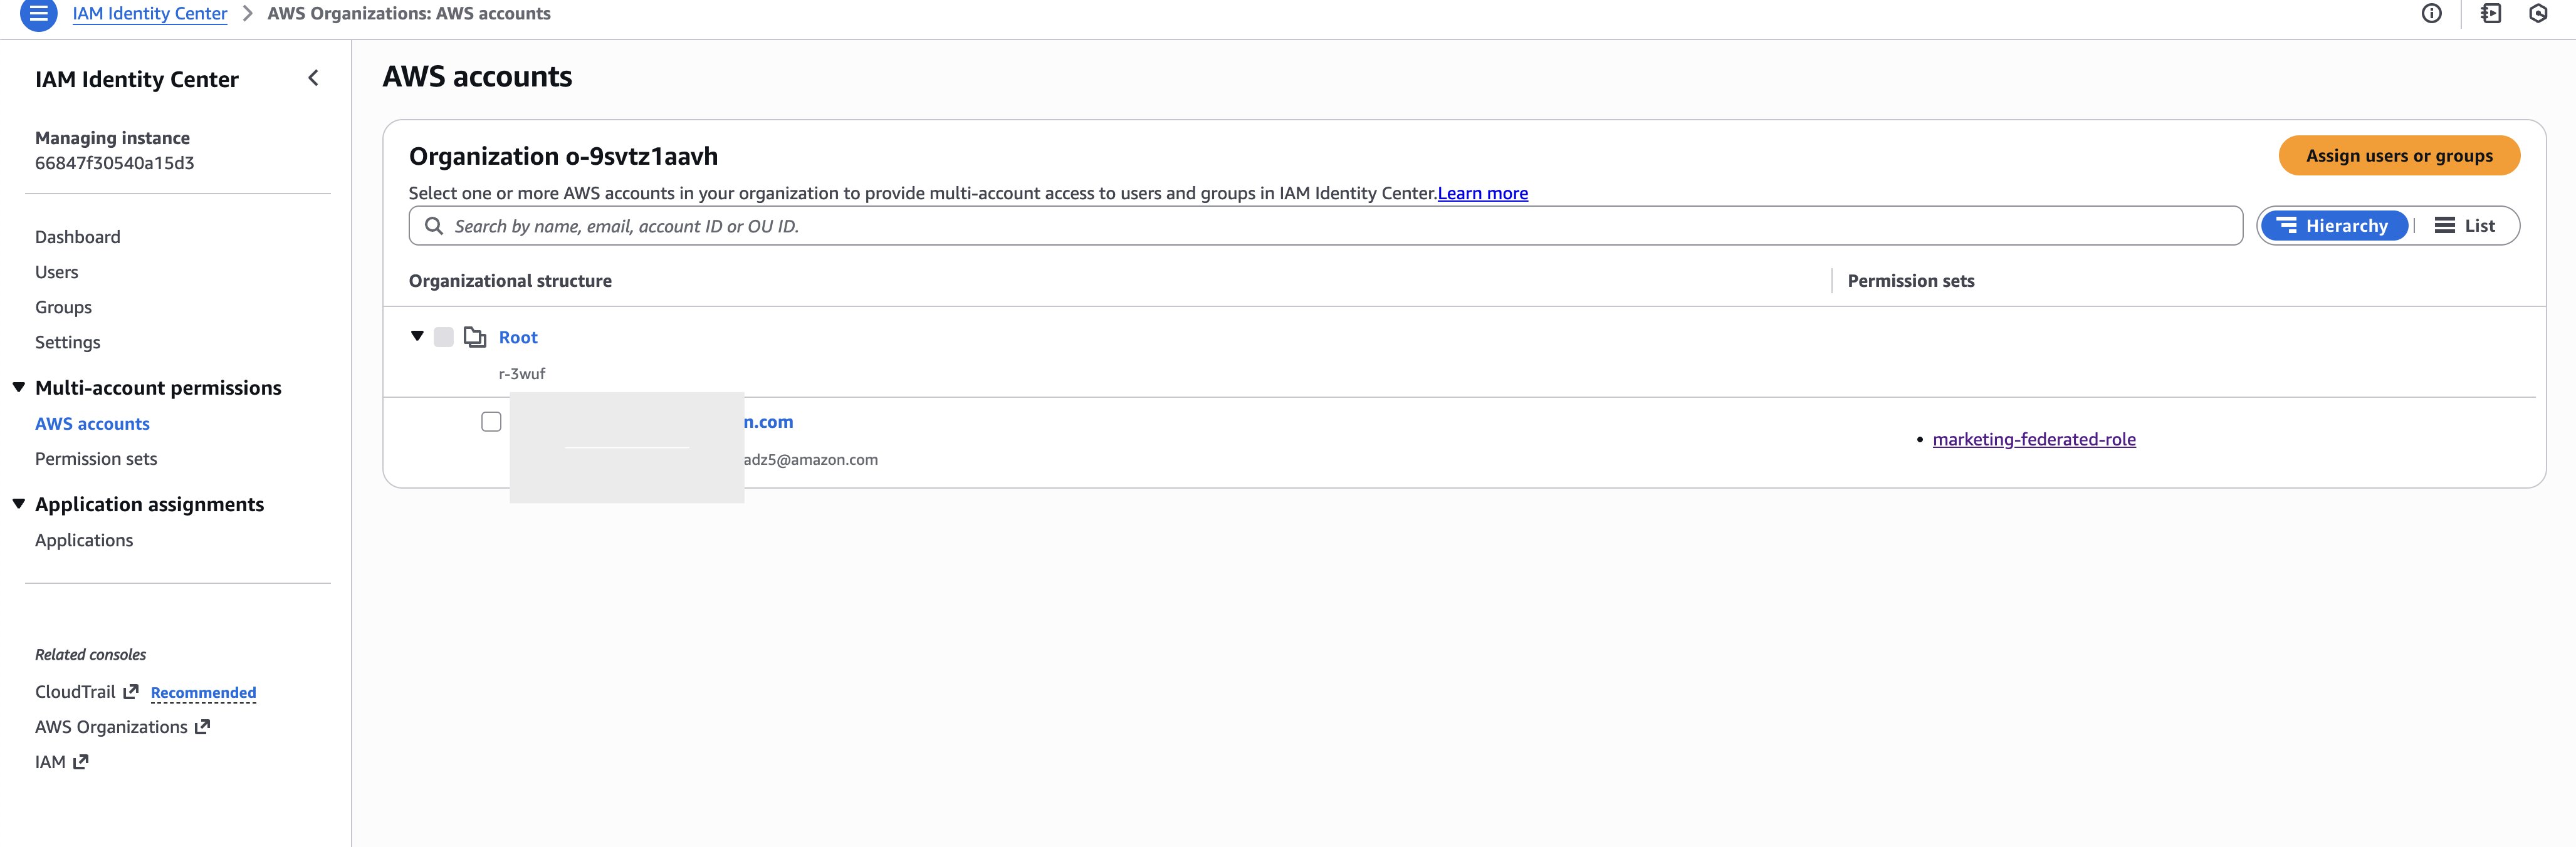
  1. Go to the AWS account section of IDC.
  2. Assign the created permission set to your AWS account.

AWS IAM Identity Center console screenshot showing AWS accounts page in hierarchy view with organization o-9svtz1aavh, displaying Root organizational unit containing AWS account n.com with marketing-federated-role permission set assigned and assign users or groups option.

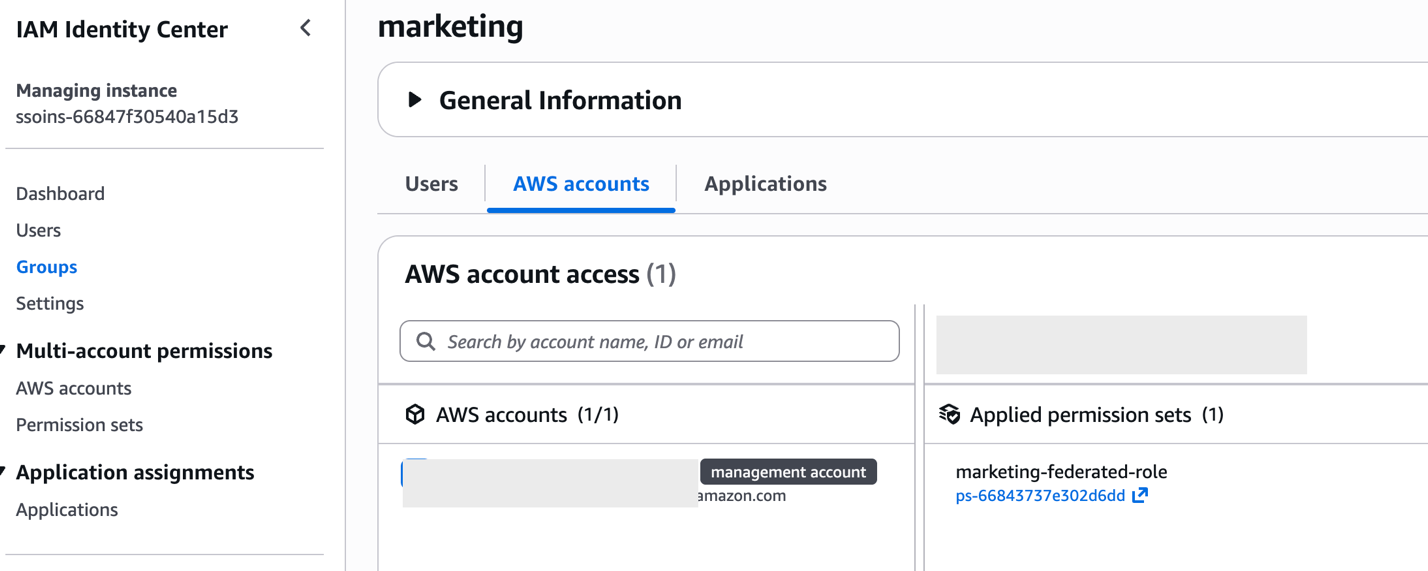
  1. For this post we assigned the permission set to marketing group, As a best practice, you should setup and grant access to groups rather than individual users.

AWS IAM Identity Center console screenshot showing marketing group details page with AWS accounts tab selected, displaying one AWS account access (management account amazon.com) with marketing-federated-role permission set applied.

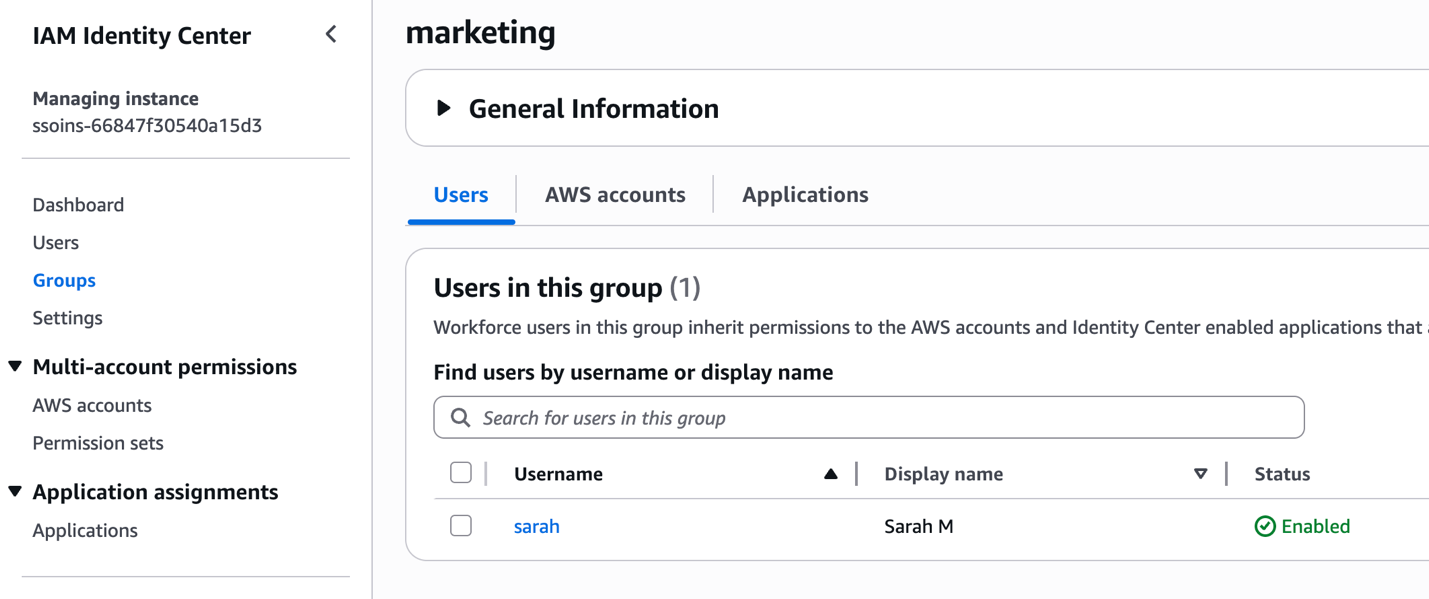
  1. Add Sarah to marketing group.

AWS IAM Identity Center console screenshot showing marketing group's Users tab with one enabled member (user sarah, Display name: Sarah M) who inherits permissions to AWS accounts and Identity Center enabled applications.

This creates a federated role that Sarah can use to access the IAM-based domain. The federated role appears as an IAM role within your account and serves as the entry point for console access.

Setting up IAM-based domain execution role

There are 2 options to setup execution role for IAM-based domain project. The execution role has a one-to-one mapping with the federated role.

Option 1 – IDC-based domain Project Role reuse

Instead of creating a new execution role and tagging it, you can configure the IAM-based domain project to directly reuse the consumer project IAM role from the IDC-based domain as the execution role. This option only needs policy changes to the consumer project IAM role. To find the IDC-based domain consumer project IAM role:

  1. Navigate to the Amazon SageMaker Unified Studio IDC-based domain portal.
  2. Open the Marketing Consumer Project.
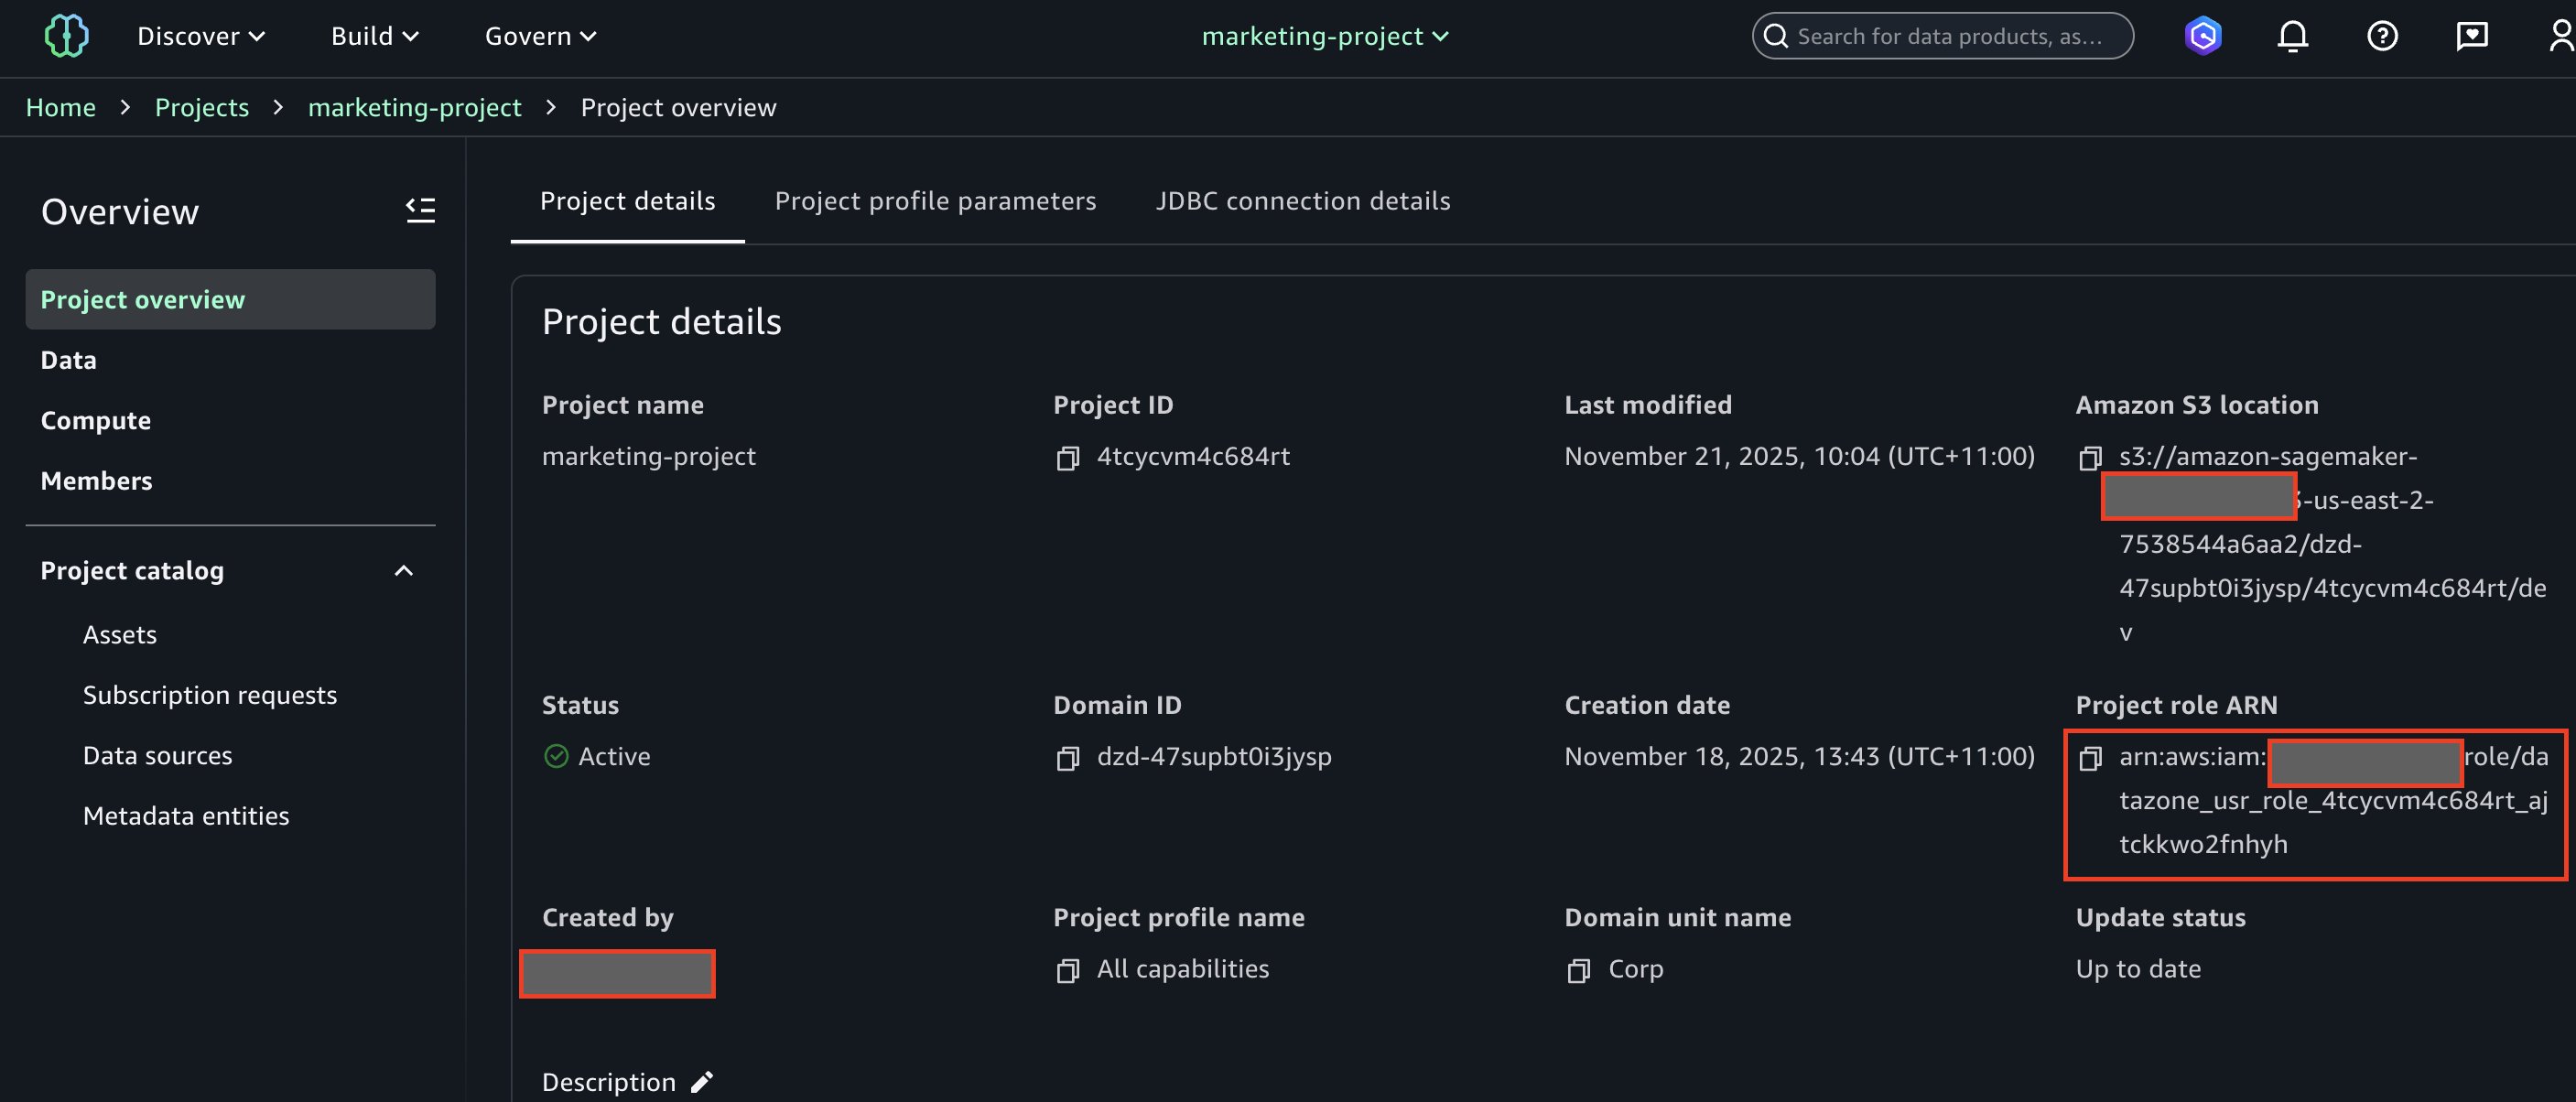
  3. Copy the project role ARN from the project overview page.

Amazon DataZone project overview page displaying marketing-project details with active status, project ID 4tcycvm4c684rt, domain ID dzd-47supbt0i3jysp, All capabilities profile, Corp domain unit, Amazon S3 location in us-east-2, and project role ARN with up-to-date status.

  1. You will need to modify this execution role’s policy with detailed instructions provided later in the blog.

Setting up IAM-based domain project for option 1

To create an IAM-based domain project that will integrate with your existing IDC-based domain permissions, complete the following steps:

  1. Log in to the AWS Console using IAM-based domain administrator.
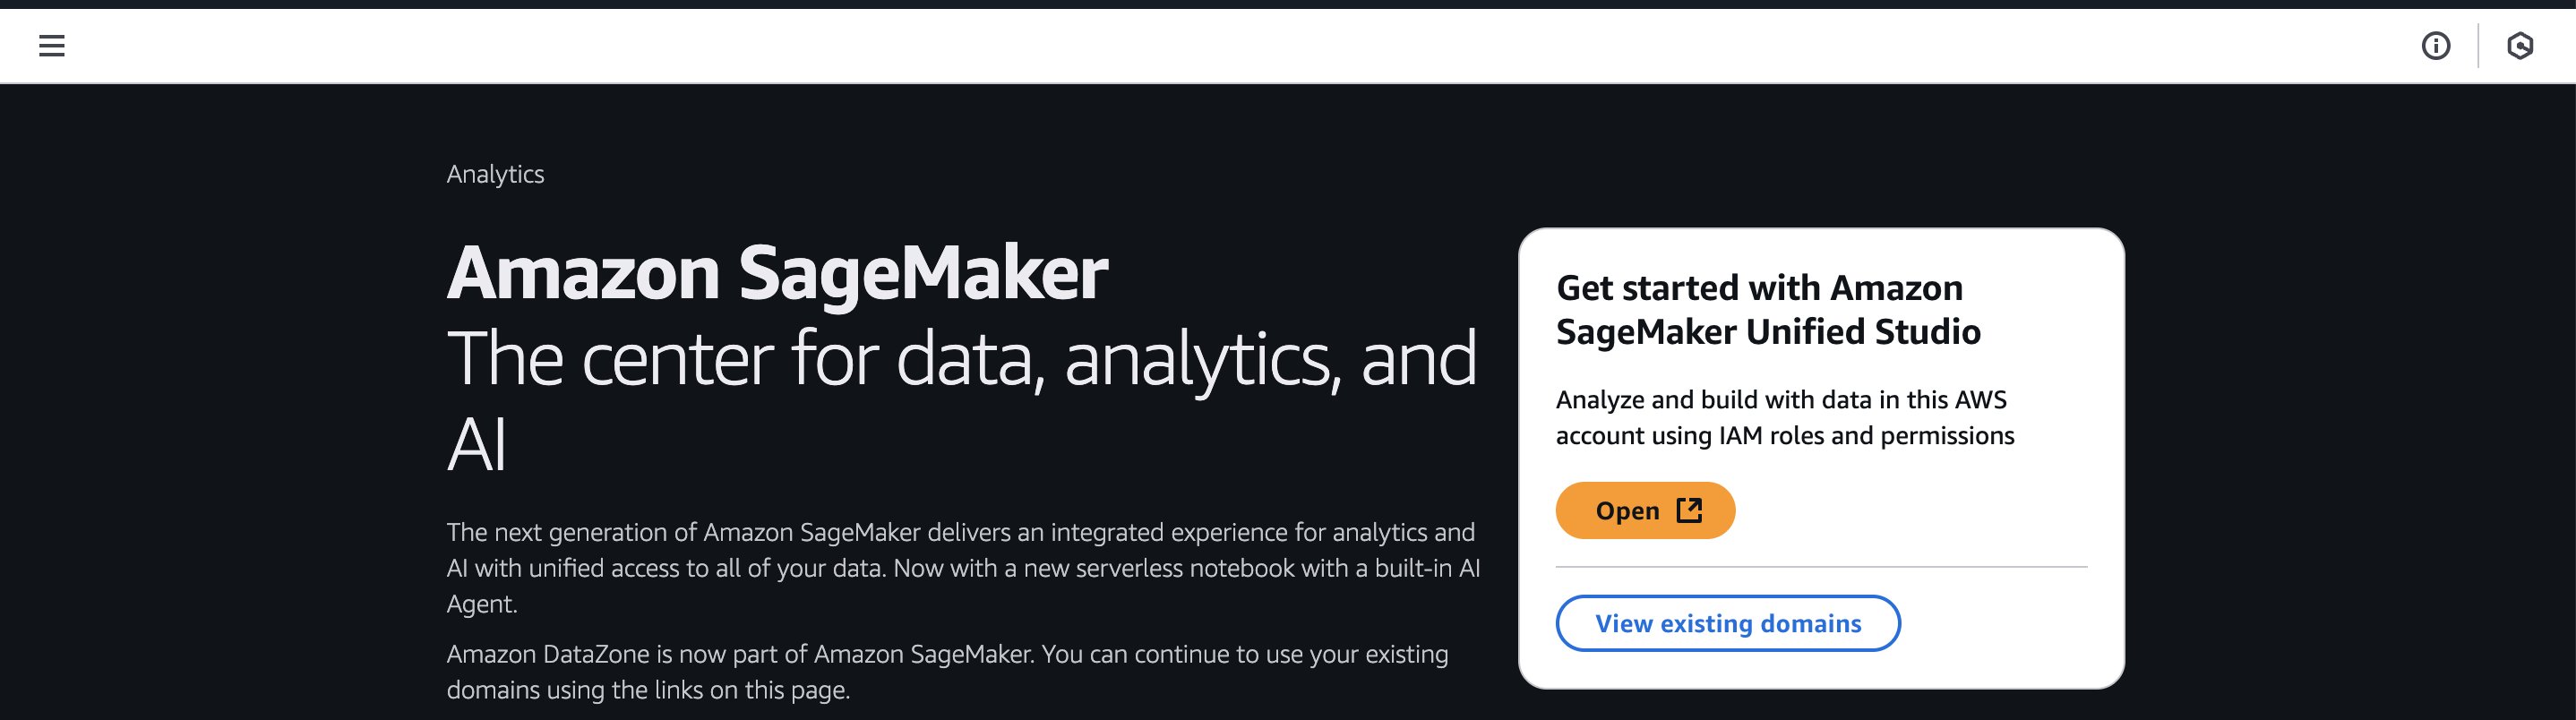
  2. Navigate to Amazon SageMaker page within console.
  3. Choose Open.

Amazon SageMaker landing page displaying "The center for data, analytics, and AI" with tagline about next-generation integrated analytics experience, serverless notebooks with built-in AI Agent, Amazon DataZone integration note, and call-to-action panel featuring "Get started with Amazon SageMaker Unified Studio" with Open button and View existing domains

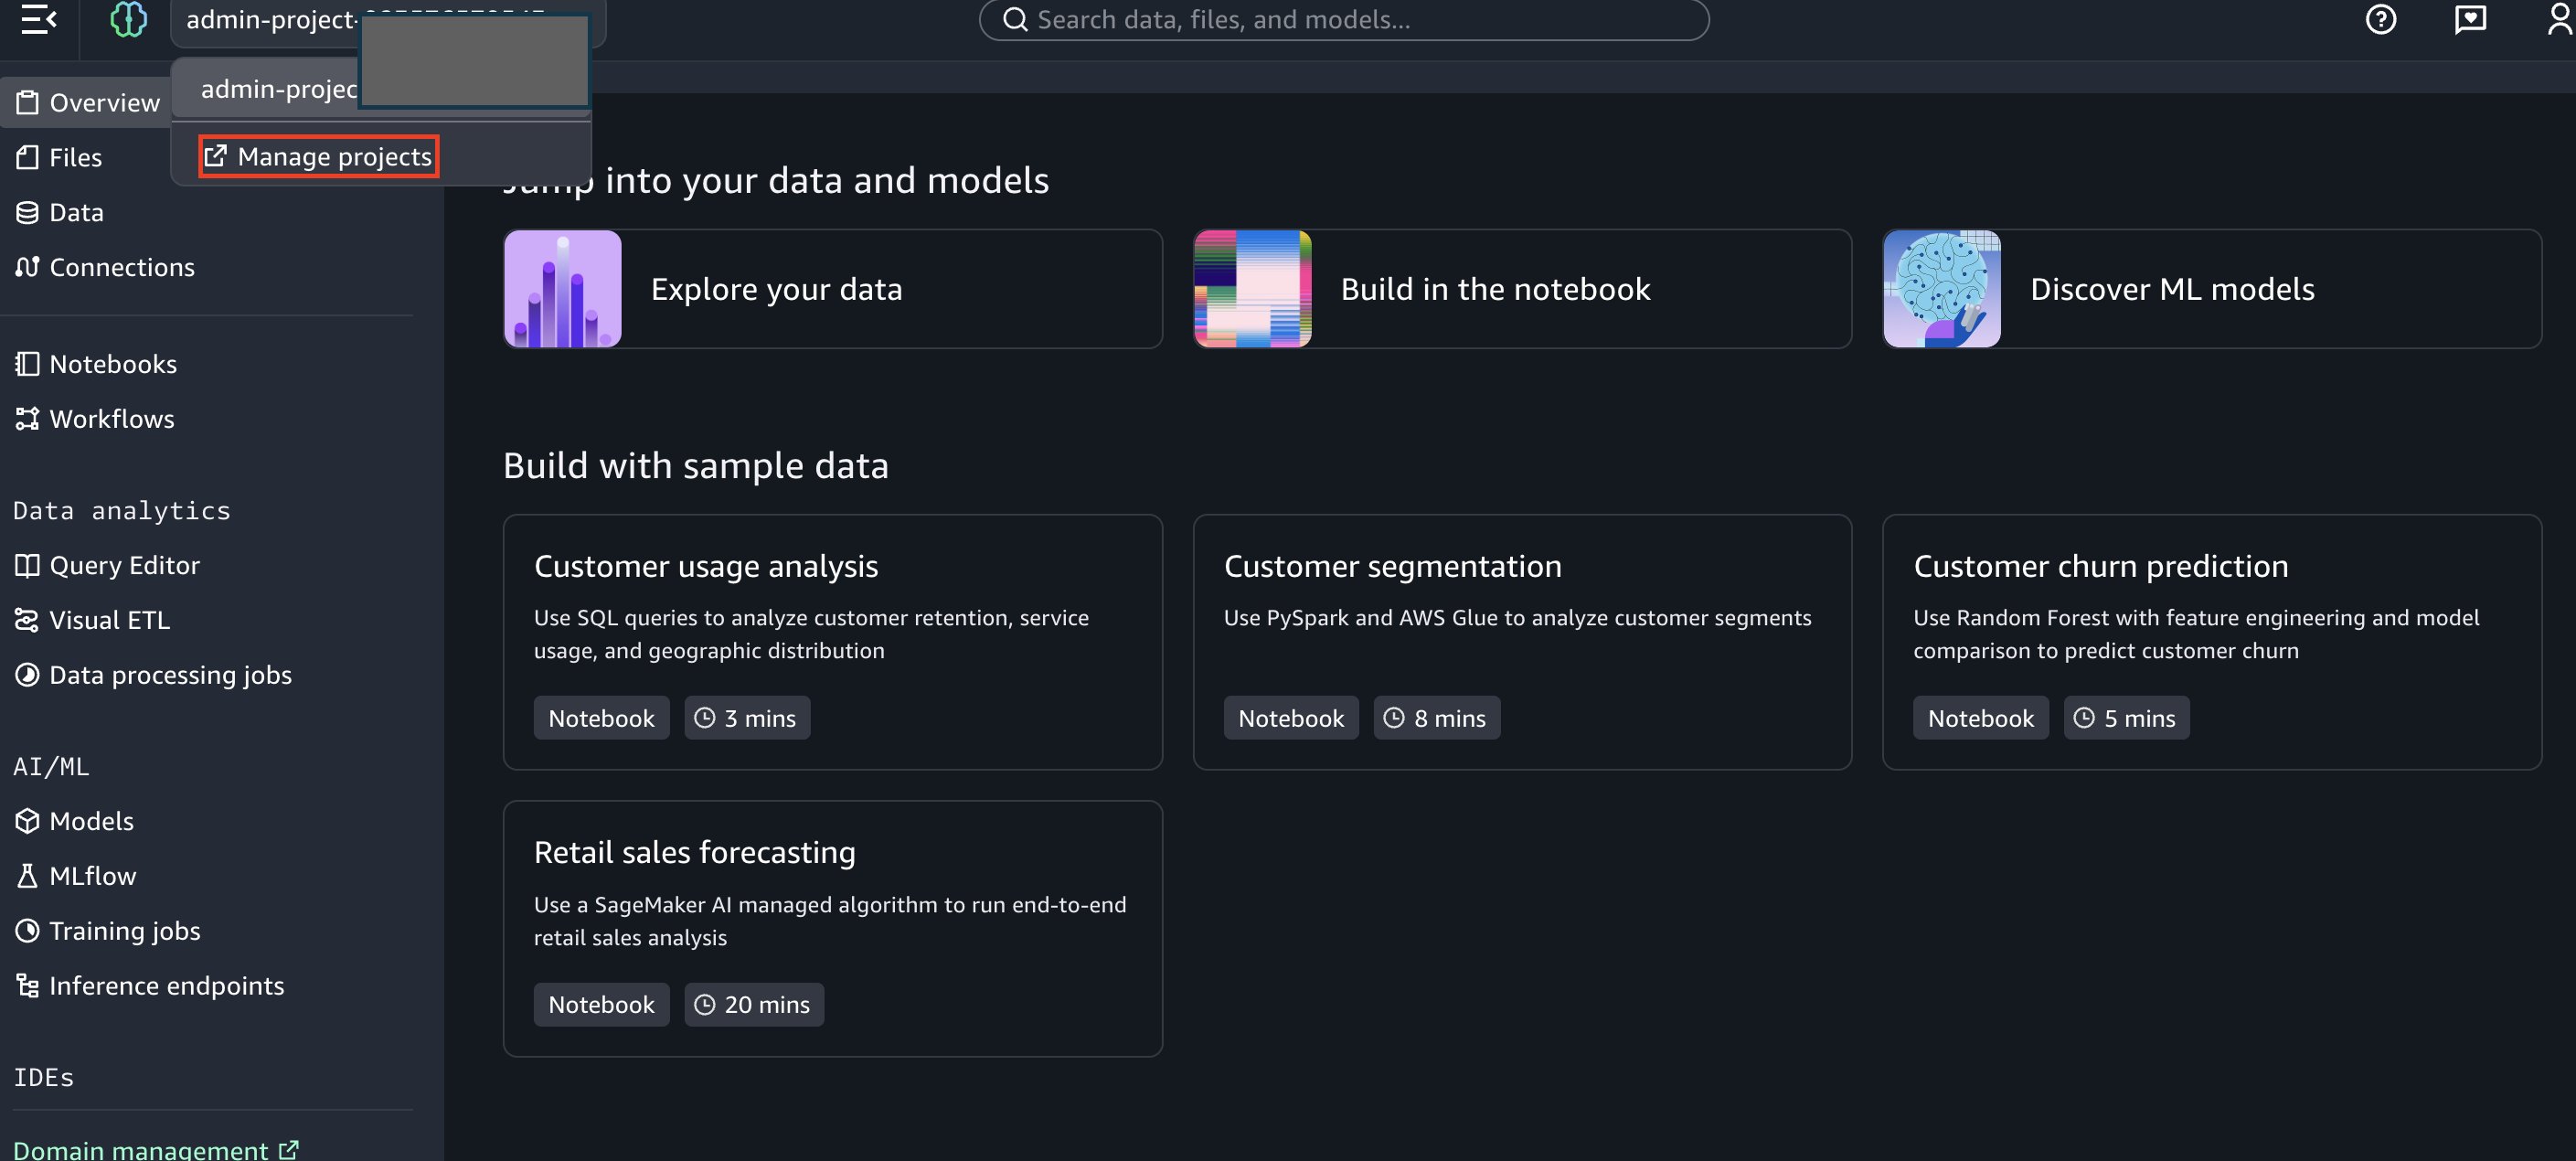
  1. Once logged in to IAM-based domain as admin, choose Manage projects.

Amazon SageMaker admin-project dashboard displaying left navigation menu with data analytics and AI/ML sections, quick-start cards for exploring data, building in notebooks, and discovering ML models, plus four sample data project templates: Customer usage analysis (3 mins), Customer segmentation (8 mins), Customer churn prediction (5 mins), and Retail sales forecasting (20 mins).

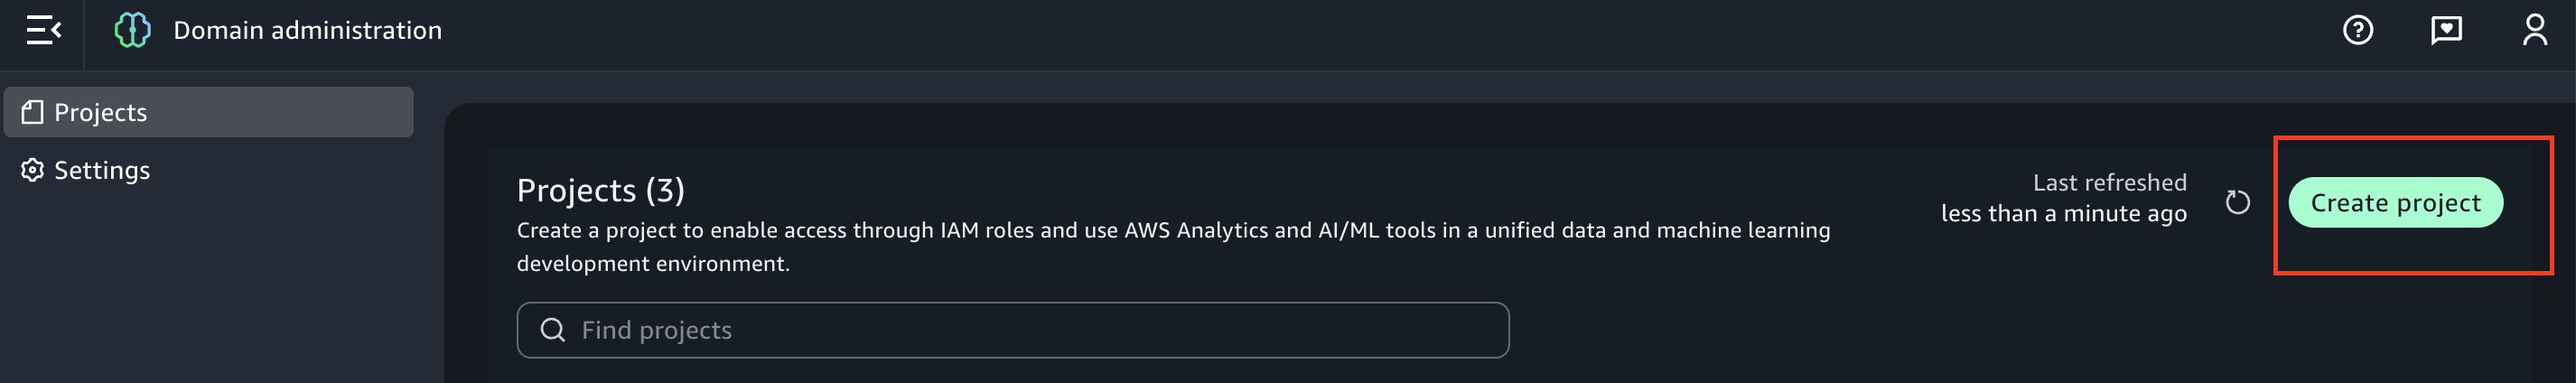
  1. Next, click on Create Project.

Amazon DataZone Domain Administration Projects page showing "Projects (3)" with description about enabling IAM role-based access to AWS Analytics and AI/ML tools, search functionality to find projects, last refreshed timestamp, and green Create project button.

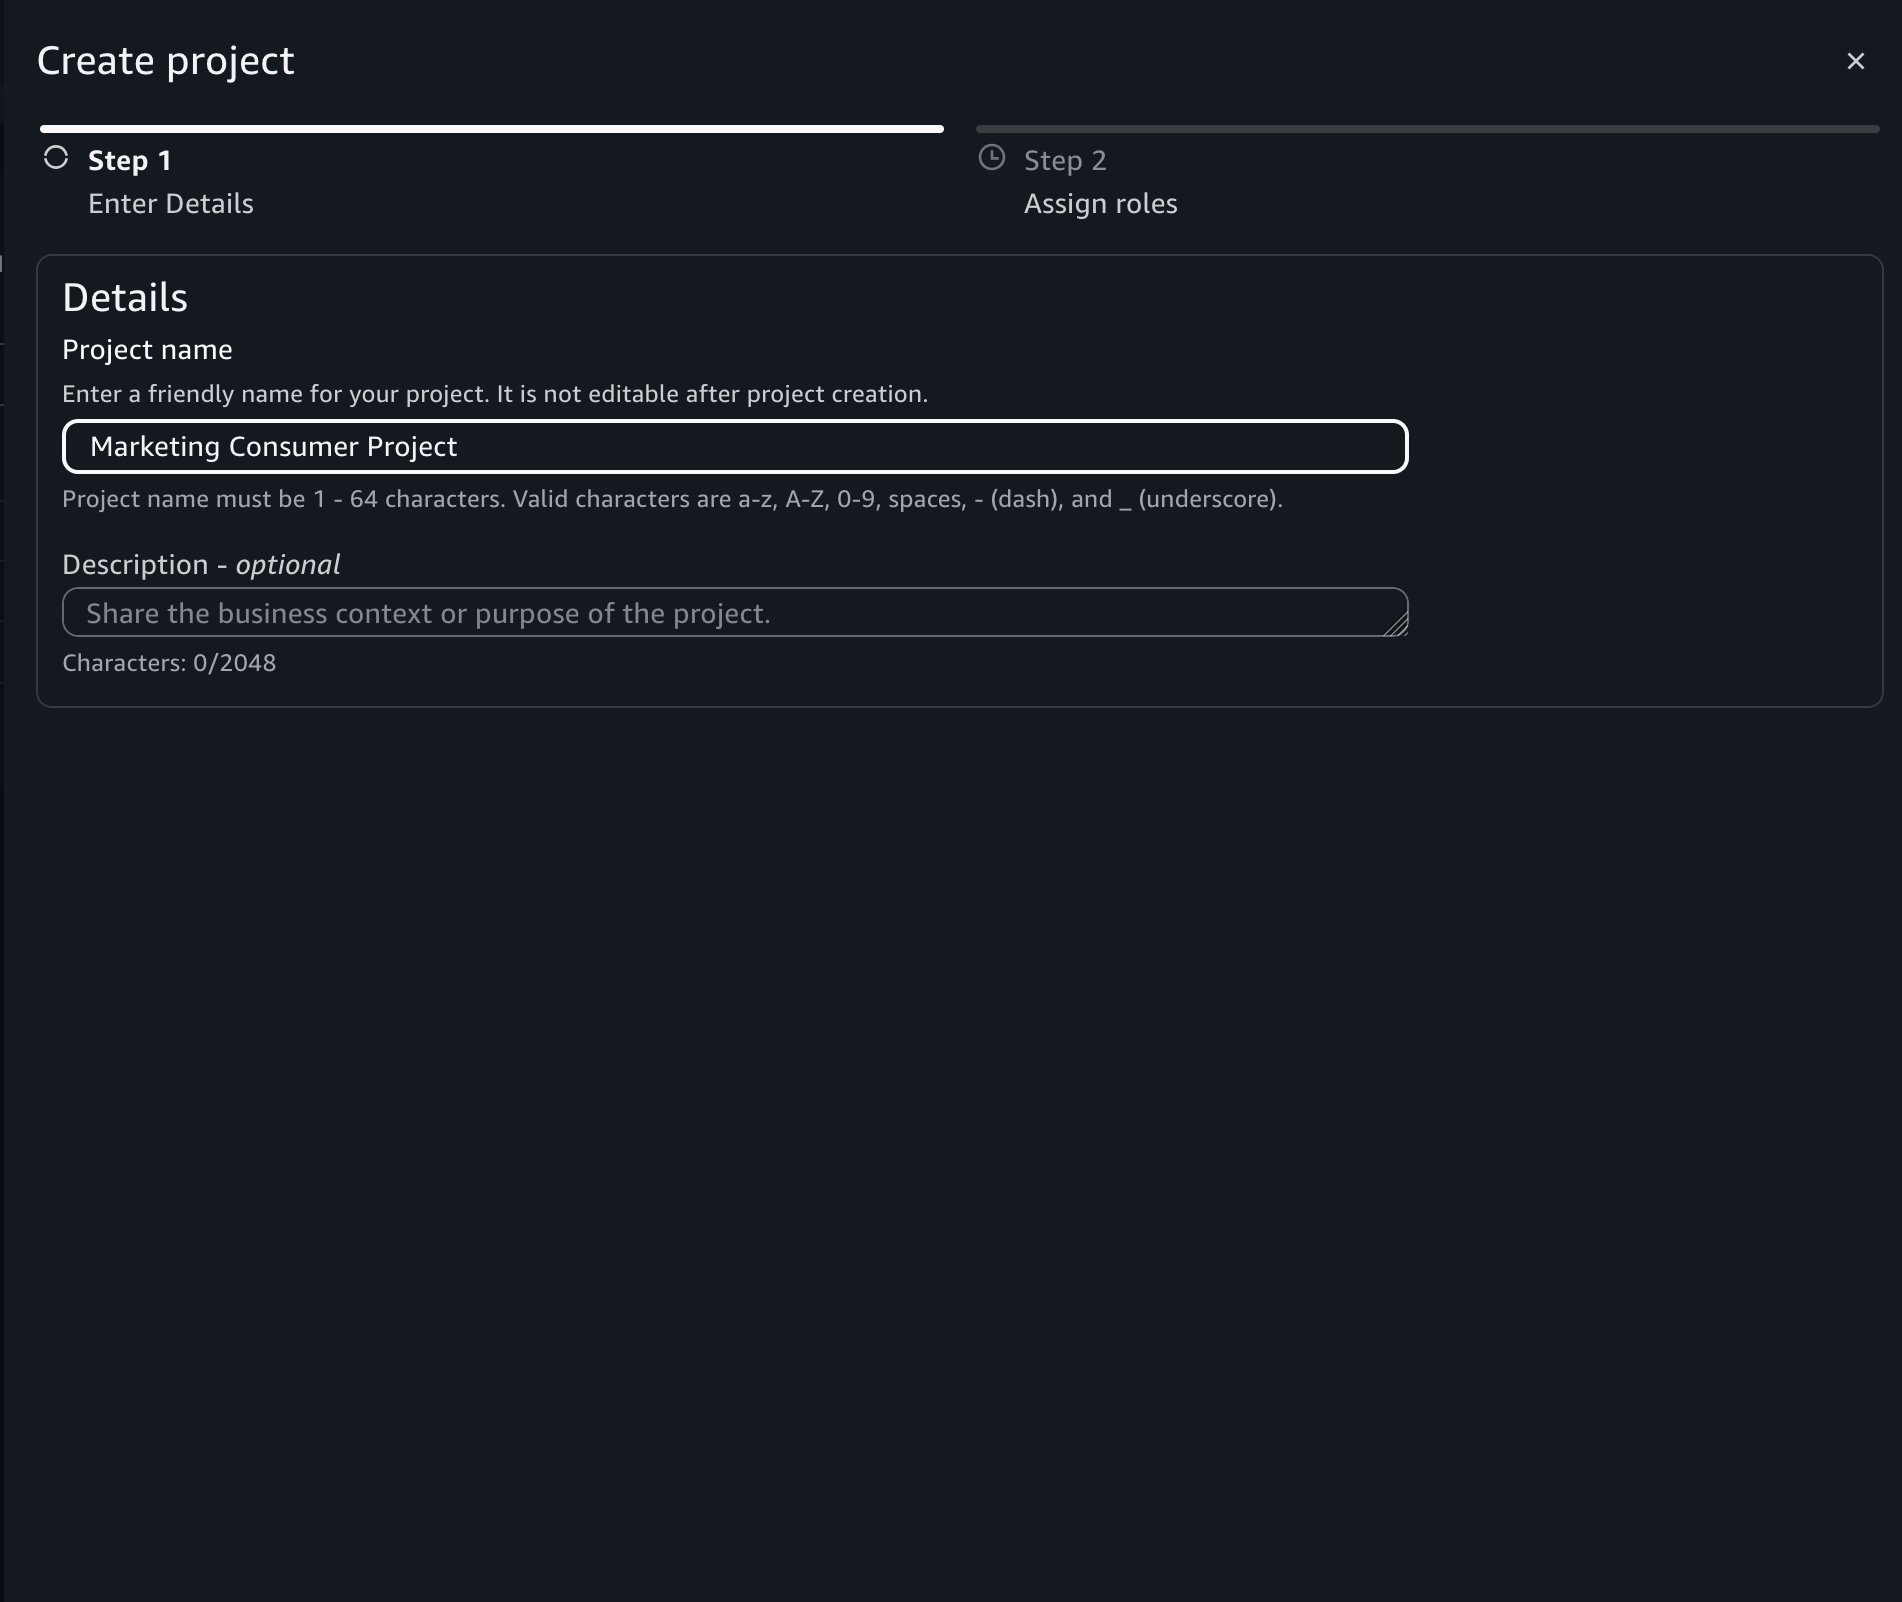
  1. Enter project name as “Marketing Consumer Project”.

Amazon DataZone Create project dialog showing Step 1 "Enter Details" with required Project name field containing "Marketing Consumer Project" (1-64 characters, a-z, A-Z, 0-9, spaces, dashes, underscores allowed) and optional Description field with 0/2048 character count, followed by Step 2 "Assign roles".

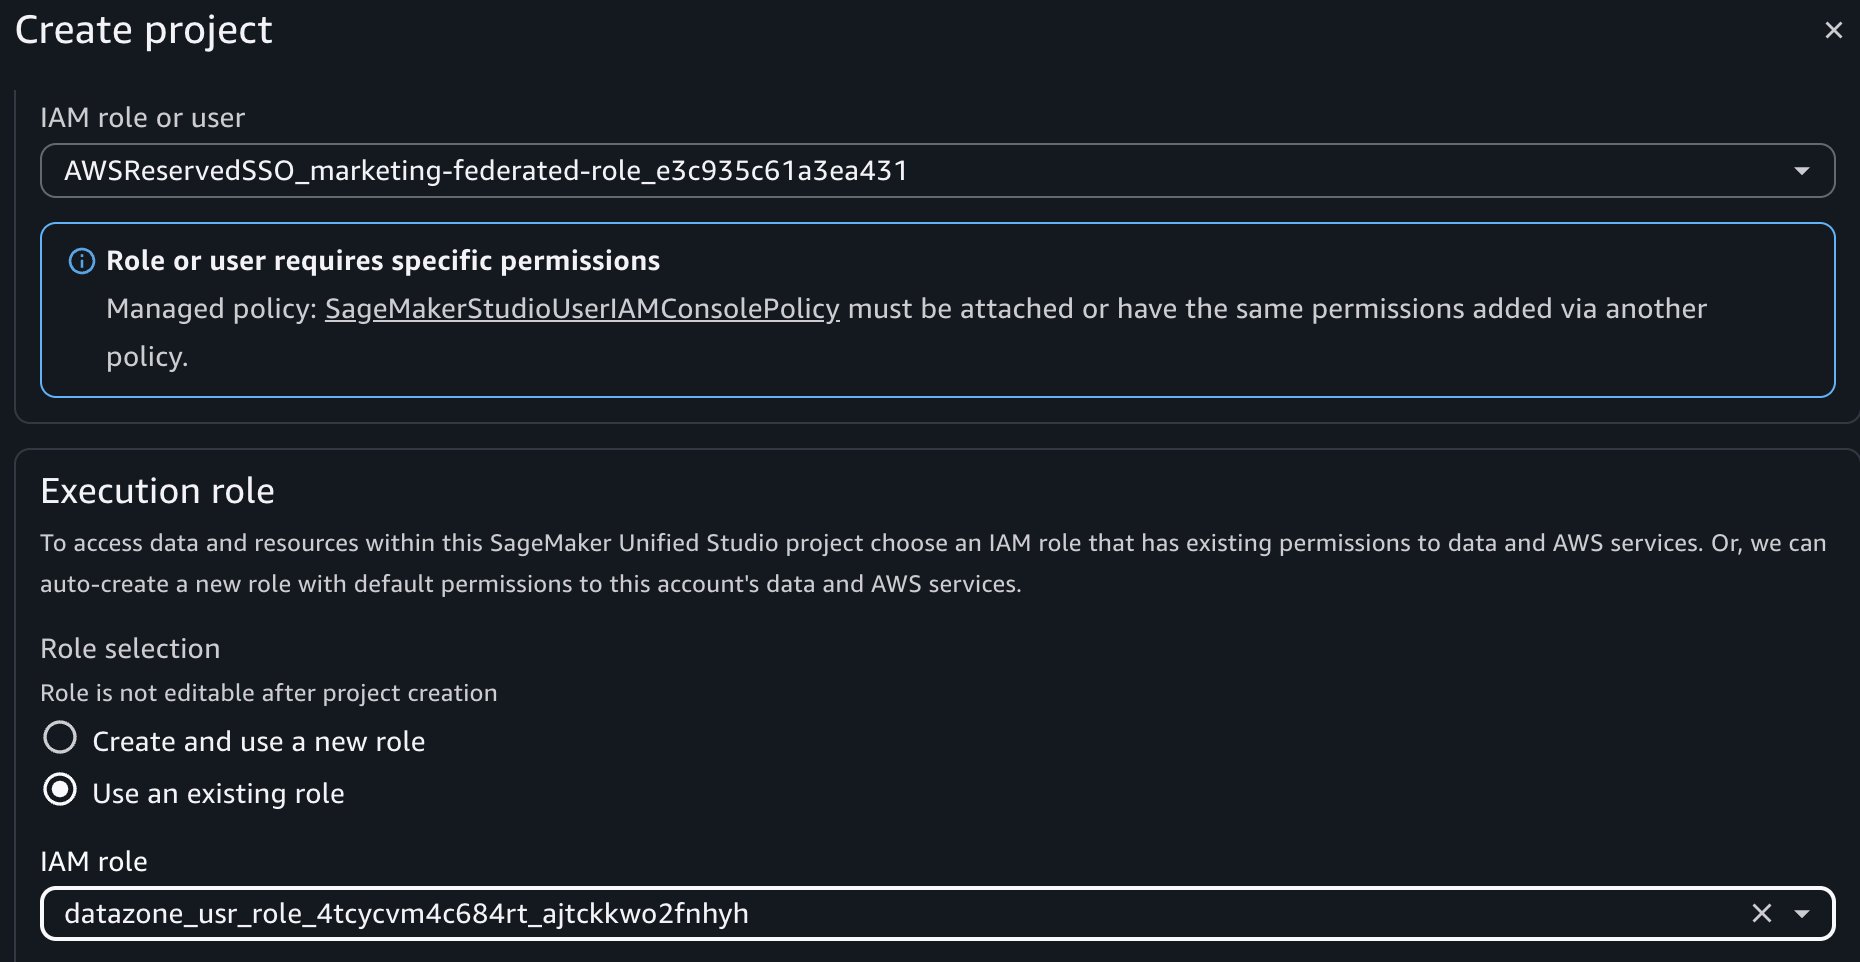
  1. During project creation, select the following crucial roles and then choose Create Project:
  • Project IAM Role: The marketing federated role created in IAM Identity Center above. This is the role in the member account that has a role name with suffix AWSReservedSSO.
  • Project Role: – Choose project role for data engineer, copied from option 1.

Amazon SageMaker Unified Studio Create project dialog showing IAM role configuration with AWSReservedSSO_marketing-federated-role selected, blue alert requiring SageMakerStudioUserIAMConsolePolicy attachment, Execution role section with "Use an existing role" option selected, and datazone_usr_role_4tcycvm4c684rt_ajtckkwo2fnhyh IAM role specified with note that role is not editable after project creation

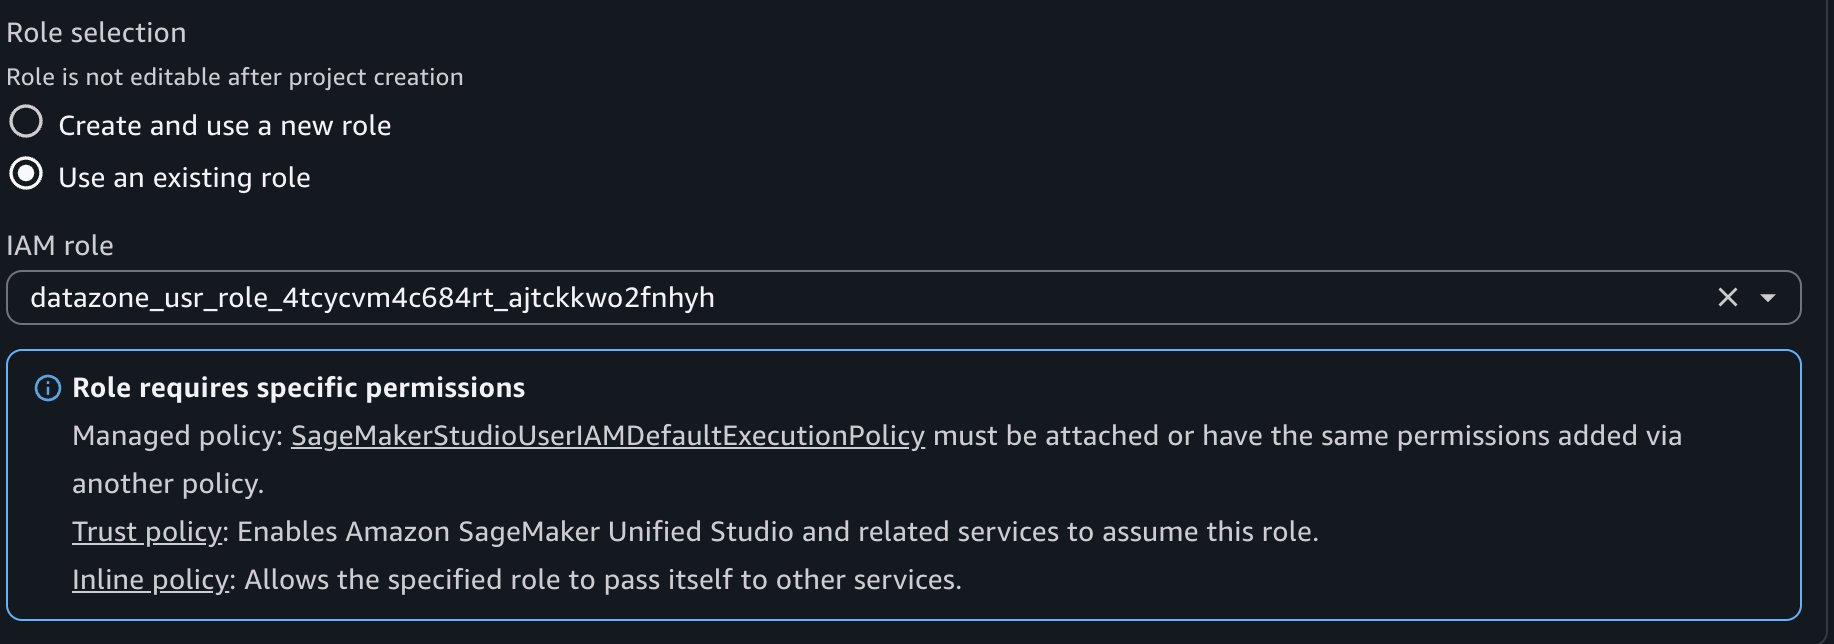
  1. Make policy changes to this project role as per the instruction on the SMUS UI page.

Amazon SageMaker Unified Studio role selection interface showing "Use an existing role" option selected with IAM role datazone_usr_role_4tcycvm4c684rt_ajtckkwo2fnhyh, blue information box displaying required permissions including SageMakerStudioUserIAMDefaultExecutionPolicy managed policy, trust policy enabling Amazon SageMaker Unified Studio service assumption, and inline policy for role pass-through, with note that role is not editable after project creation.

Option 2 – Bring your own execution role. 

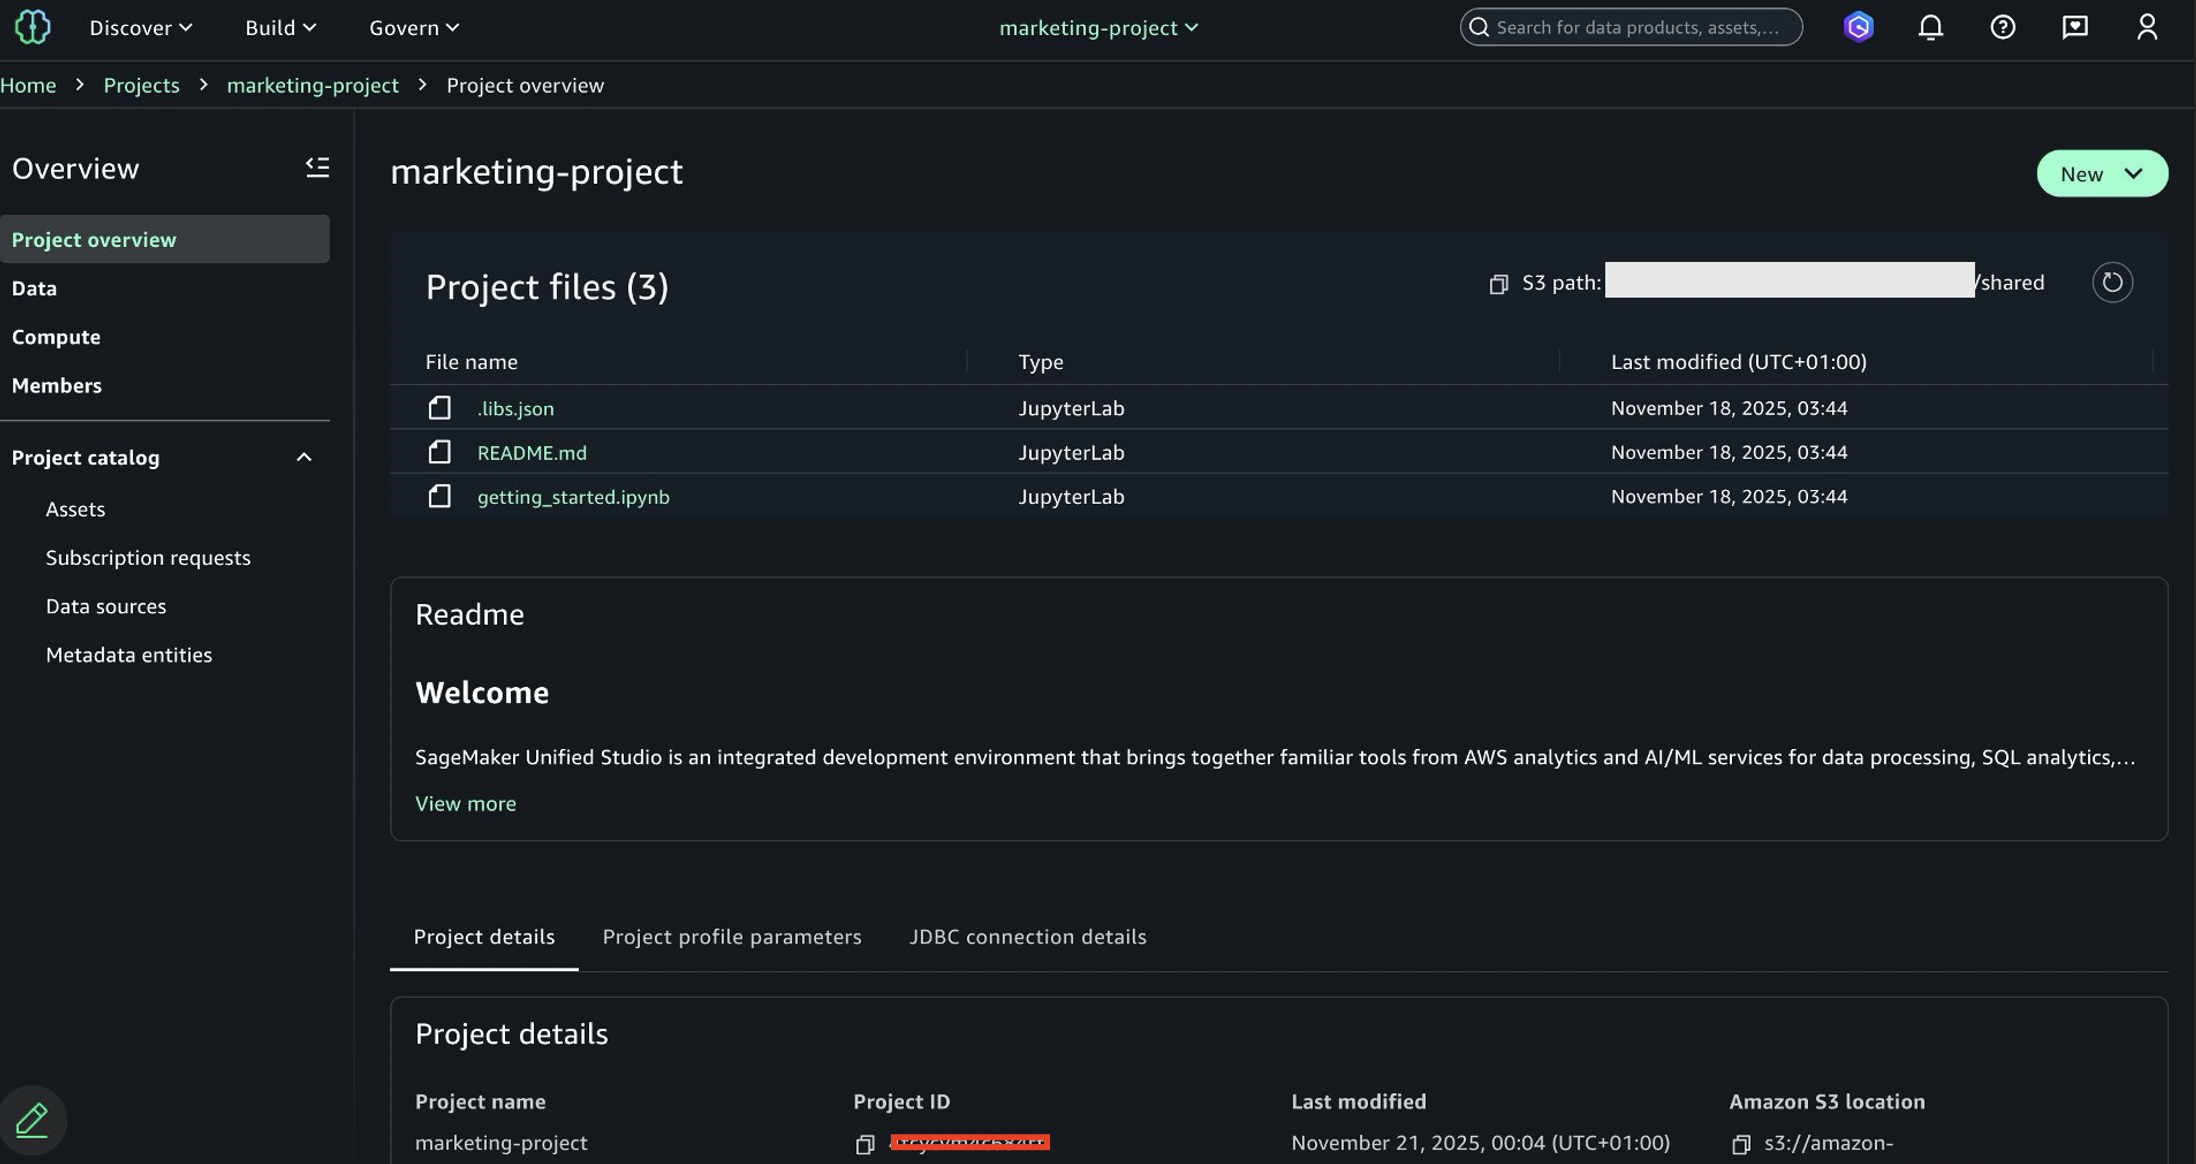
To create an IAM-based domain project that will integrate with your existing IDC-based domain permissions., you must tag the execution role for permission propagation. Amazon SageMaker Catalog and AWS Lake Formation use attribute-based access control, which means permissions can be inherited based on resource tags. For this option, you will need consumer project ID.To find the IDC-based domain consumer project ID:

  1. Navigate to the Amazon SageMaker Unified Studio IDC-based domain portal.
  2. Open the Marketing Consumer Project.
  3. Copy the project ID from the project details.

Amazon SageMaker Unified Studio marketing-project overview page displaying navigation breadcrumb (Home > Projects > marketing-project > Project overview), left sidebar menu with Project overview, Data, Compute, Members, and Project catalog sections, Project files section listing 3 JupyterLab files (.libs.json, README.md, getting_started.ipynb) last modified November 18, 2025, Readme section with Welcome heading describing SageMaker Unified Studio, and Project details tab showing project name, ID, last modified date November 21, 2025, and Amazon S3 location.” width=”2196″ height=”1164″></p>
<h3>Setting up IAM-based domain project for option 2</h3>
<p>Complete the following steps:</p>
<ol>
<li>Create another project with name “Marketing Consumer Project 2” in the IAM-based domain while logged in as admin.</li>
<li>During project creation, select the following roles:
<ol type=

  • Federated Role: The marketing federated role created in IAM Identity Center above.
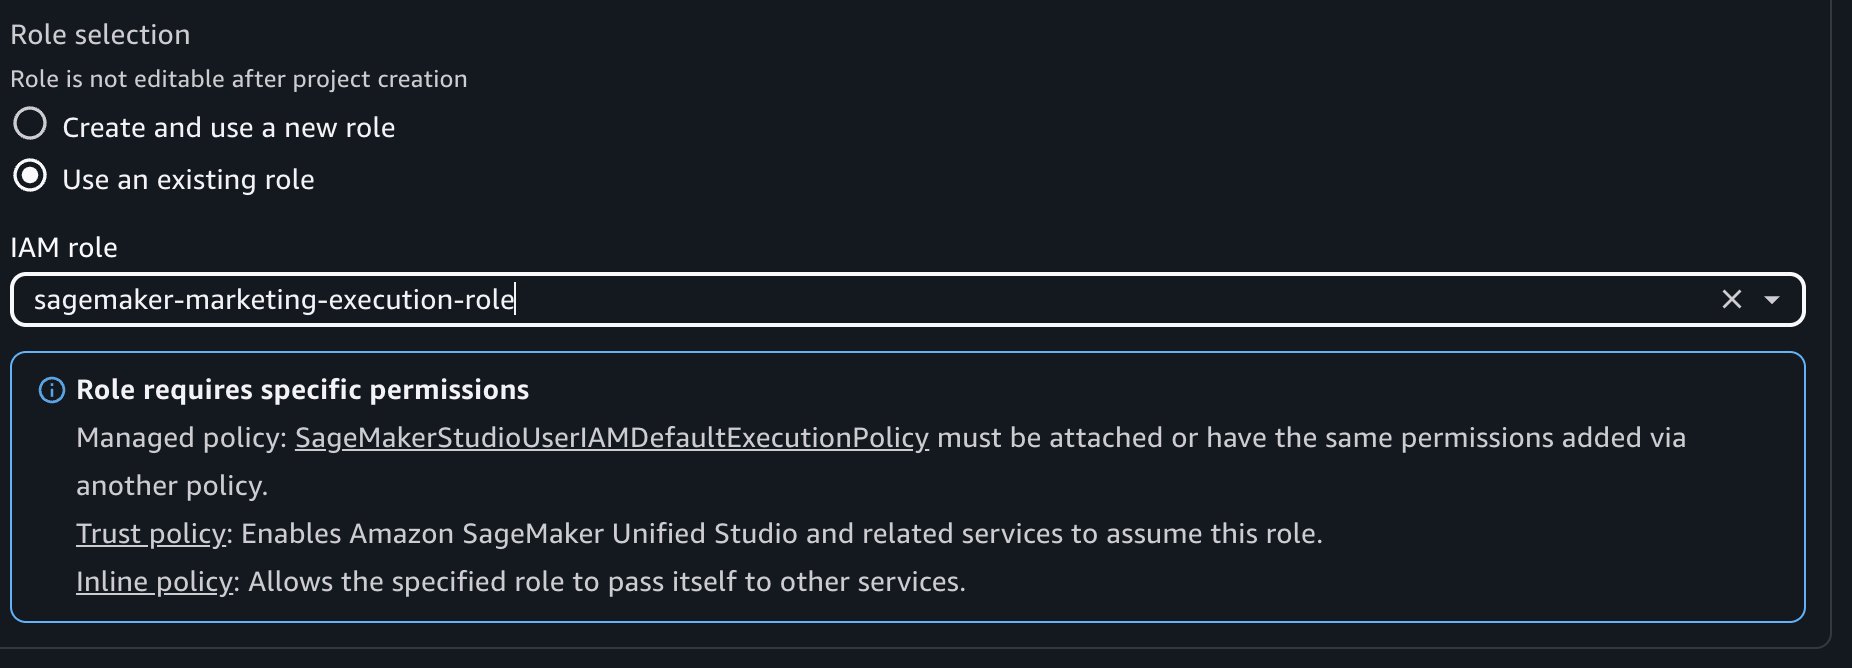
  • Execution Role: – Choose execution role from option 2.
  • Make policy changes to this execution role as per the instruction.
  • Amazon SageMaker Unified Studio role selection interface showing "Use an existing role" option selected with IAM role field containing "sagemaker-marketing-execution-role", blue information box displaying required permissions including SageMakerStudioUserIAMDefaultExecutionPolicy managed policy, trust policy enabling Amazon SageMaker Unified Studio and related services to assume the role, and inline policy allowing role pass-through to other services, with note that role is not editable after project creation

    1. Next, navigate to the IAM console and locate the execution role created for your IAM-based domain consumer project.
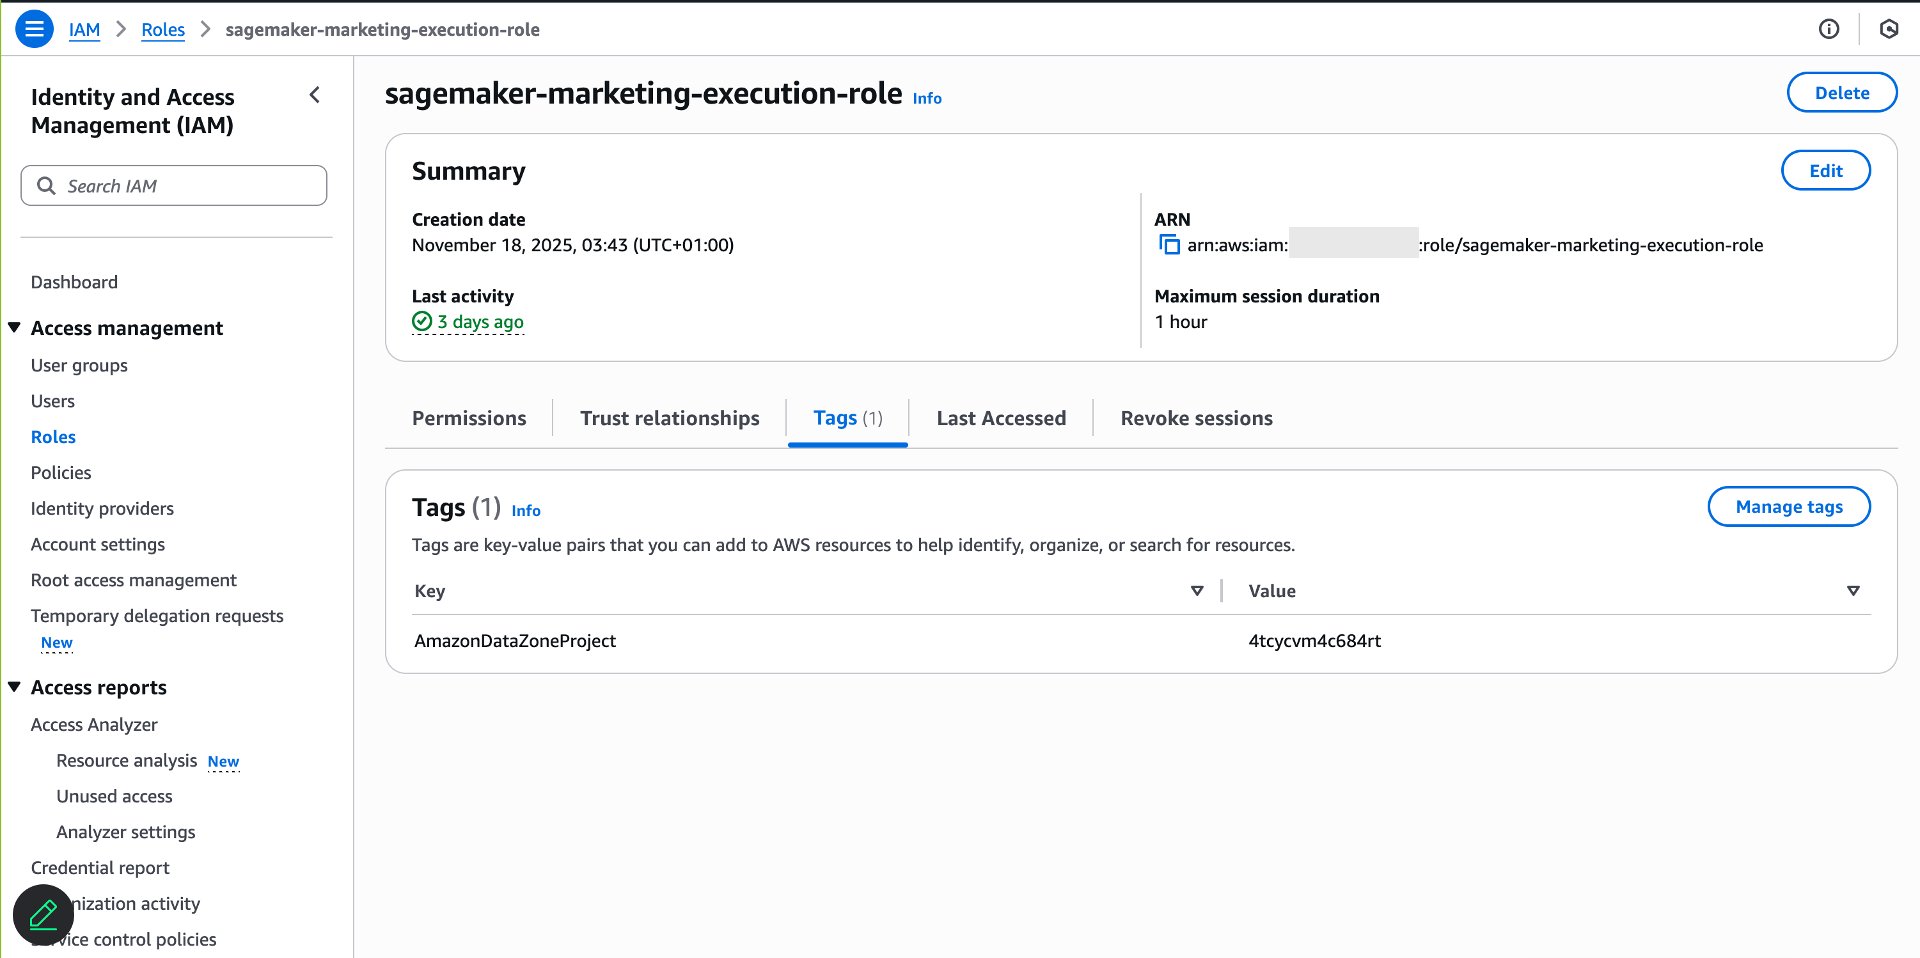
    2. Add the following tag, this step relies on ABAC policies with projectId for subscriptions.
    • Key: AmazonDatazoneProject
    • Value: The project ID from your Amazon SageMaker Unified Studio IDC-based domain consumer project

    AWS IAM console displaying sagemaker-marketing-execution-role details page with Summary section showing creation date November 18, 2025, last activity 3 days ago, ARN arn:aws:iam::role/sagemaker-marketing-execution-role, 1-hour maximum session duration, five tabs (Permissions, Trust relationships, Tags (1), Last Accessed, Revoke sessions), and Tags section displaying one tag with Key "AmazonDataZoneProject" and Value "4tcycvm4c684rt" with Delete, Edit, and Manage tags buttons available.

    This tag configuration results in data access grant from IDC-based domain consumer project to the IAM-based domain project execution role.

    Verify data access in the IAM-based domain

    After tagging the execution role, verify that permissions are set up correctly.Complete the following steps:

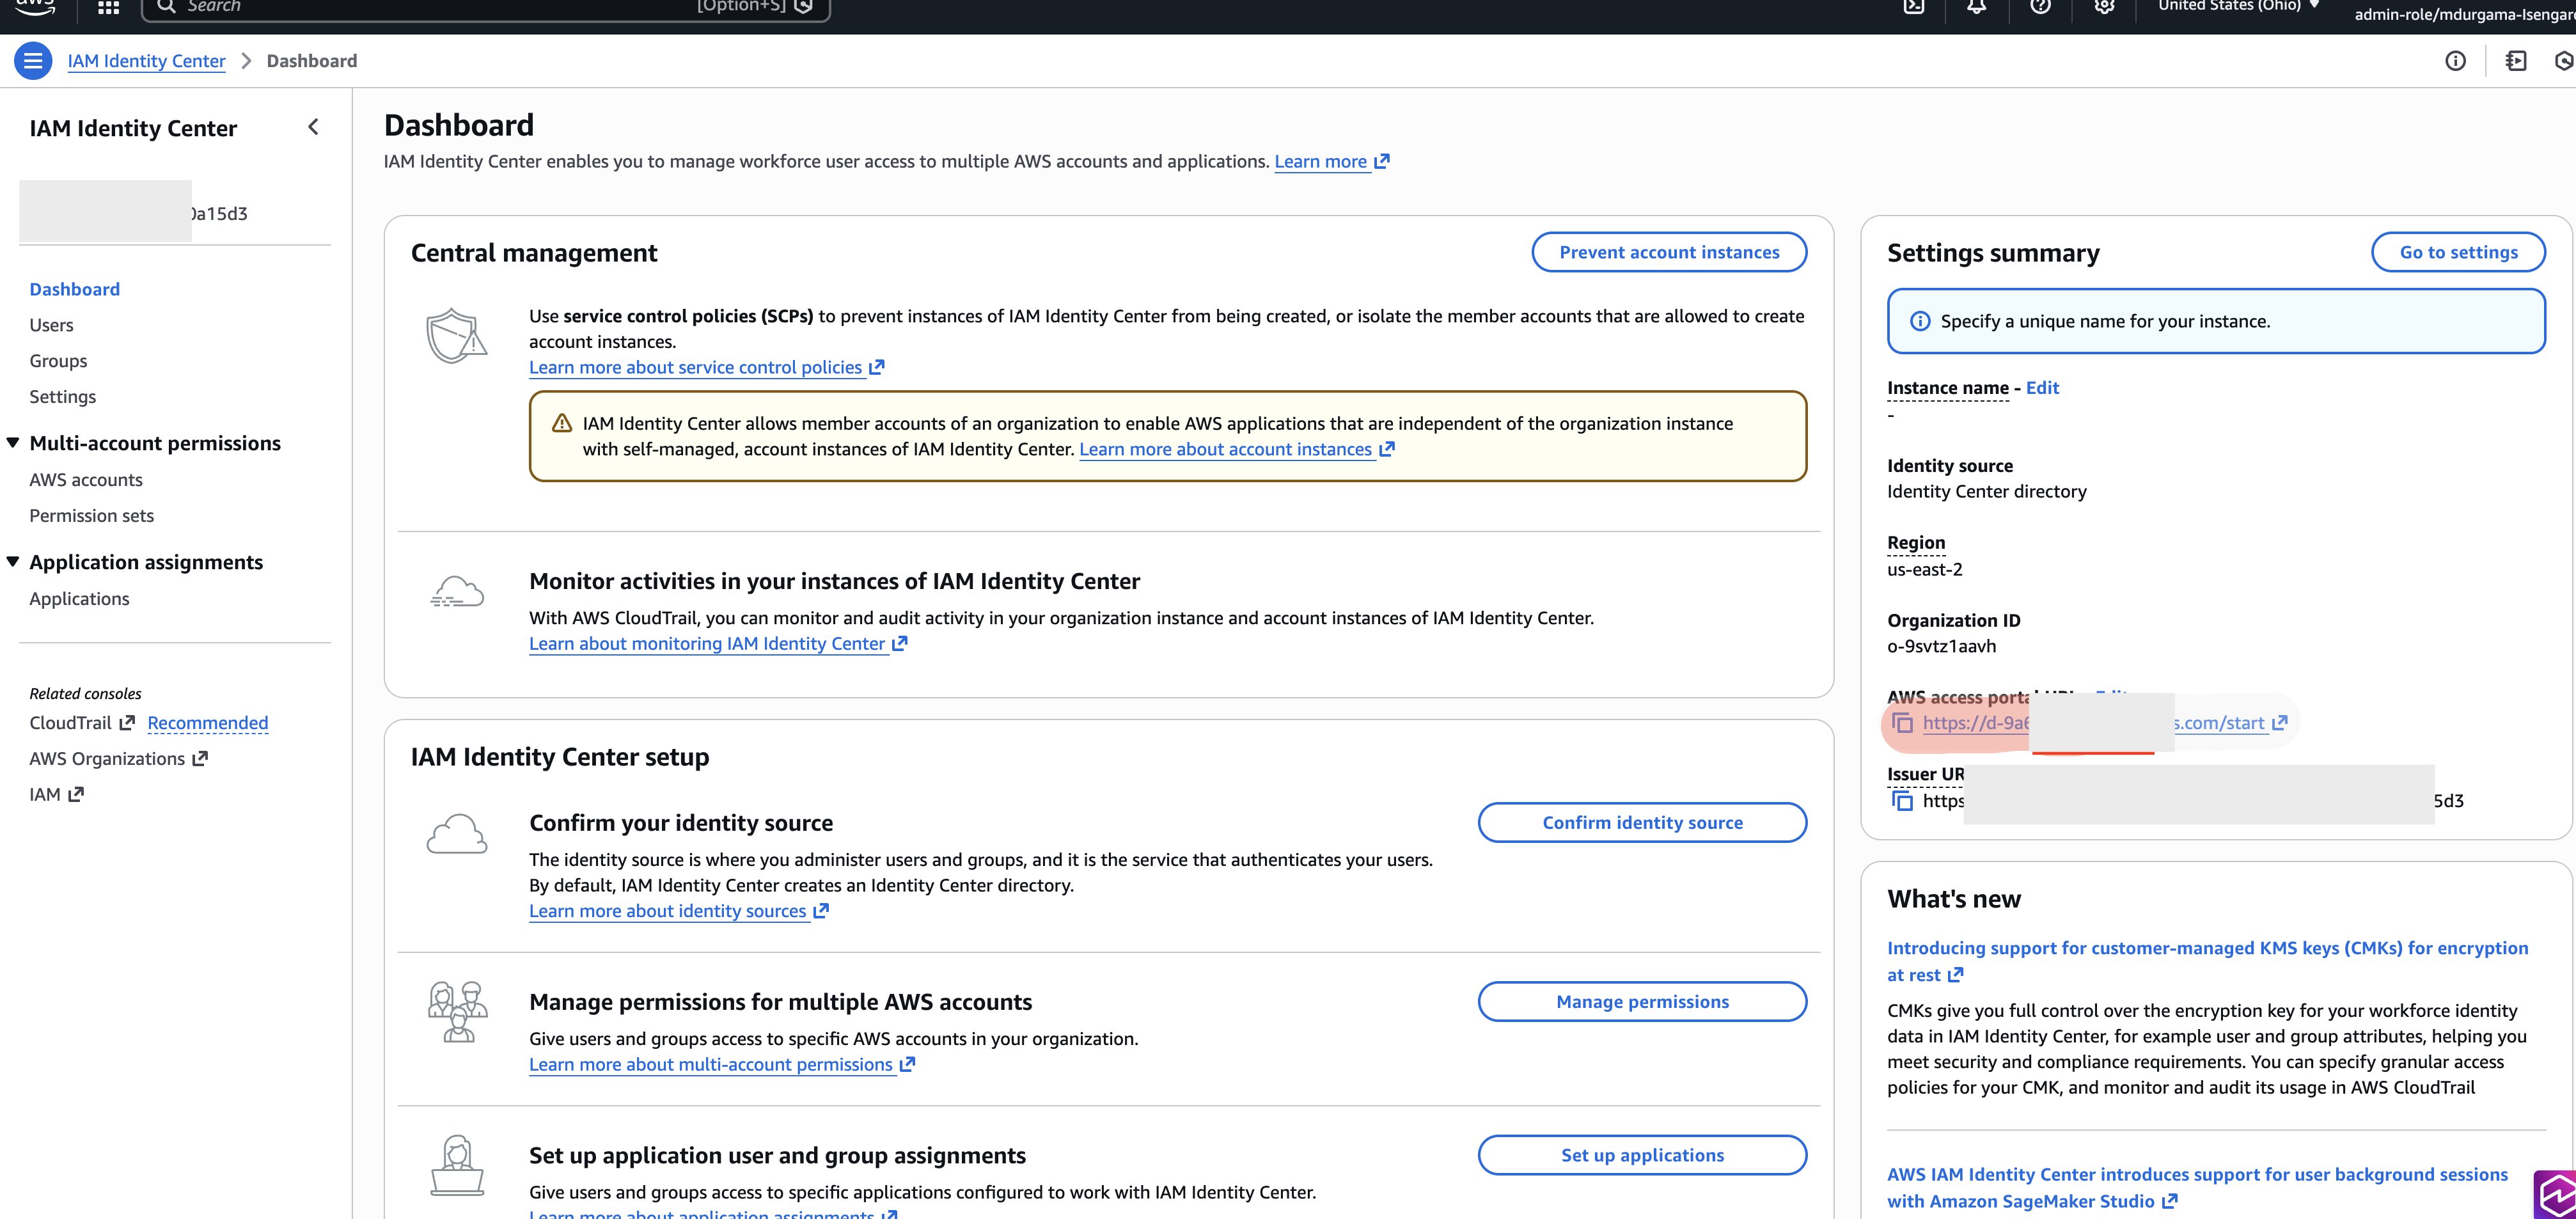
    1. Use the SSO URL to log into the SSO Identity Center as Sarah.

    AWS IAM Identity Center Dashboard displaying left navigation menu with Dashboard, Users, Groups, Settings, Multi-account permissions (AWS accounts, Permission sets), and Application assignments sections; central management panel showing service control policies guidance with yellow warning banner about member account instances and CloudTrail monitoring section; IAM Identity Center setup area with three action cards for confirming identity source, managing multi-account permissions, and setting up application assignments; right panel Settings summary showing Identity Center directory as identity source, us-east-2 region, organization ID o-9svtz1aavh, AWS access portal URL, and issuer URL; What's new section highlighting customer-managed KMS keys support and Amazon SageMaker Studio user background sessions; Related consoles links to CloudTrail, AWS Organizations, and IAM.

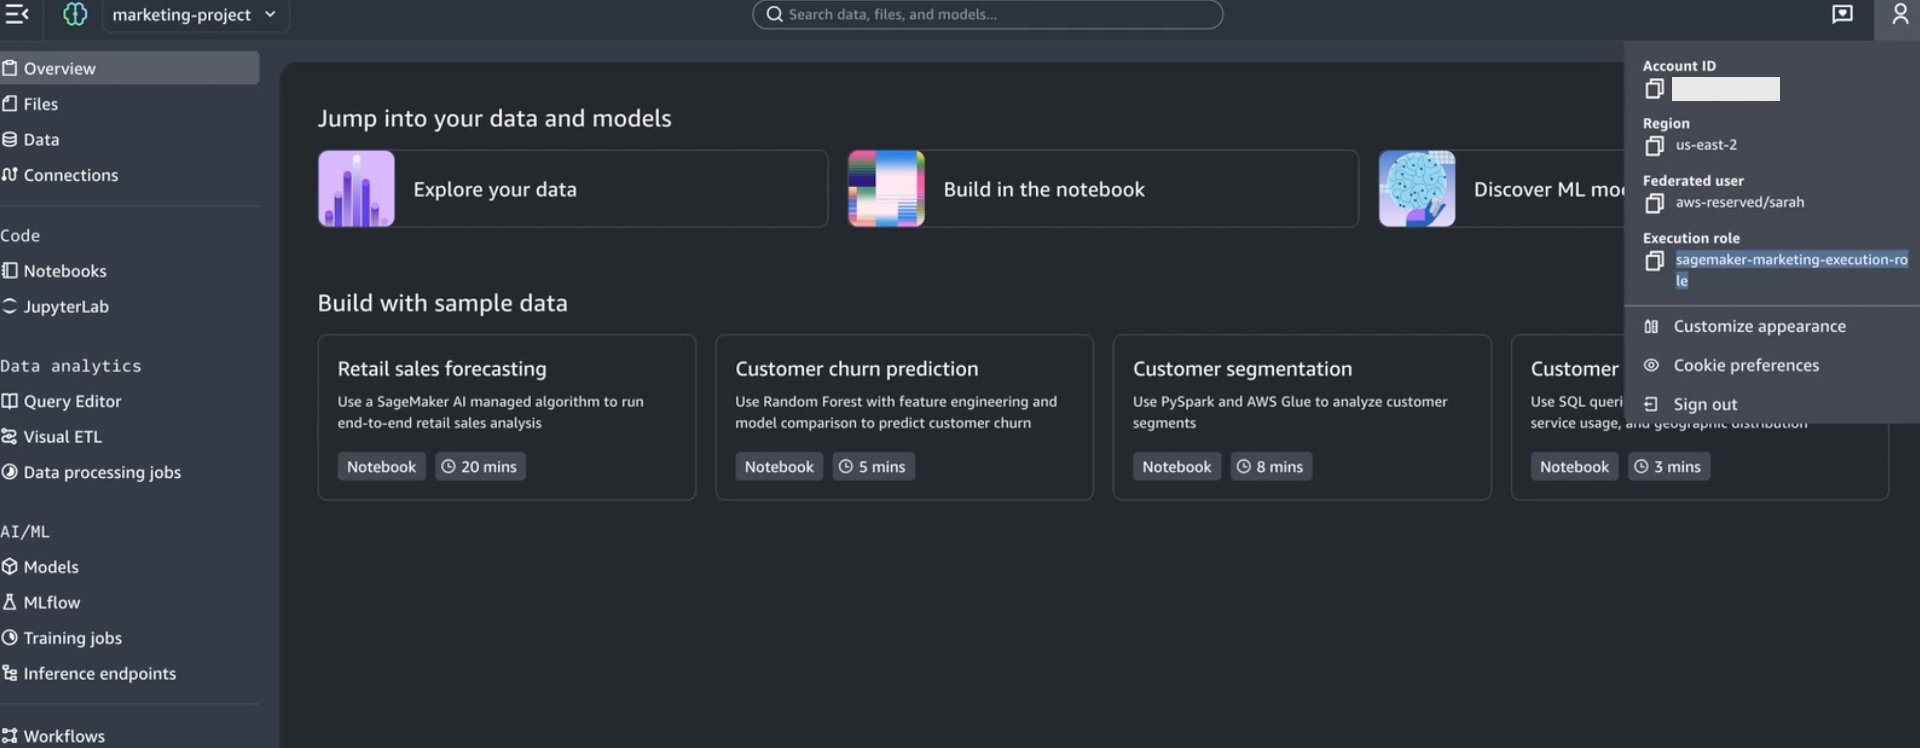
    1. Open the AWS console using federated role created earlier in setting federated role section.
    2. Navigate to Amazon SageMaker.
    3. Choose Amazon SageMaker Unified Studio IAM-based domain option (this will show up if project is already created with federated role).

    Amazon SageMaker Unified Studio marketing-project dashboard displaying left navigation menu with Overview, Files, Data, Connections, Code (Notebooks, JupyterLab), Data analytics (Query Editor, Visual ETL, Data processing jobs), and AI/ML sections (Models, MLflow, Training jobs, Inference endpoints); main content area showing "Jump into your data and models" with three quick-start cards (Explore your data, Build in the notebook, Discover ML models) and four sample data projects: Retail sales forecasting (20 mins), Customer churn prediction (5 mins), Customer segmentation (8 mins), and Customer usage analysis (3 mins); top-right panel displaying account details with us-east-2 region, federated user aws-reserved/sarah, and execution role sagemaker-marketing-execution-role.

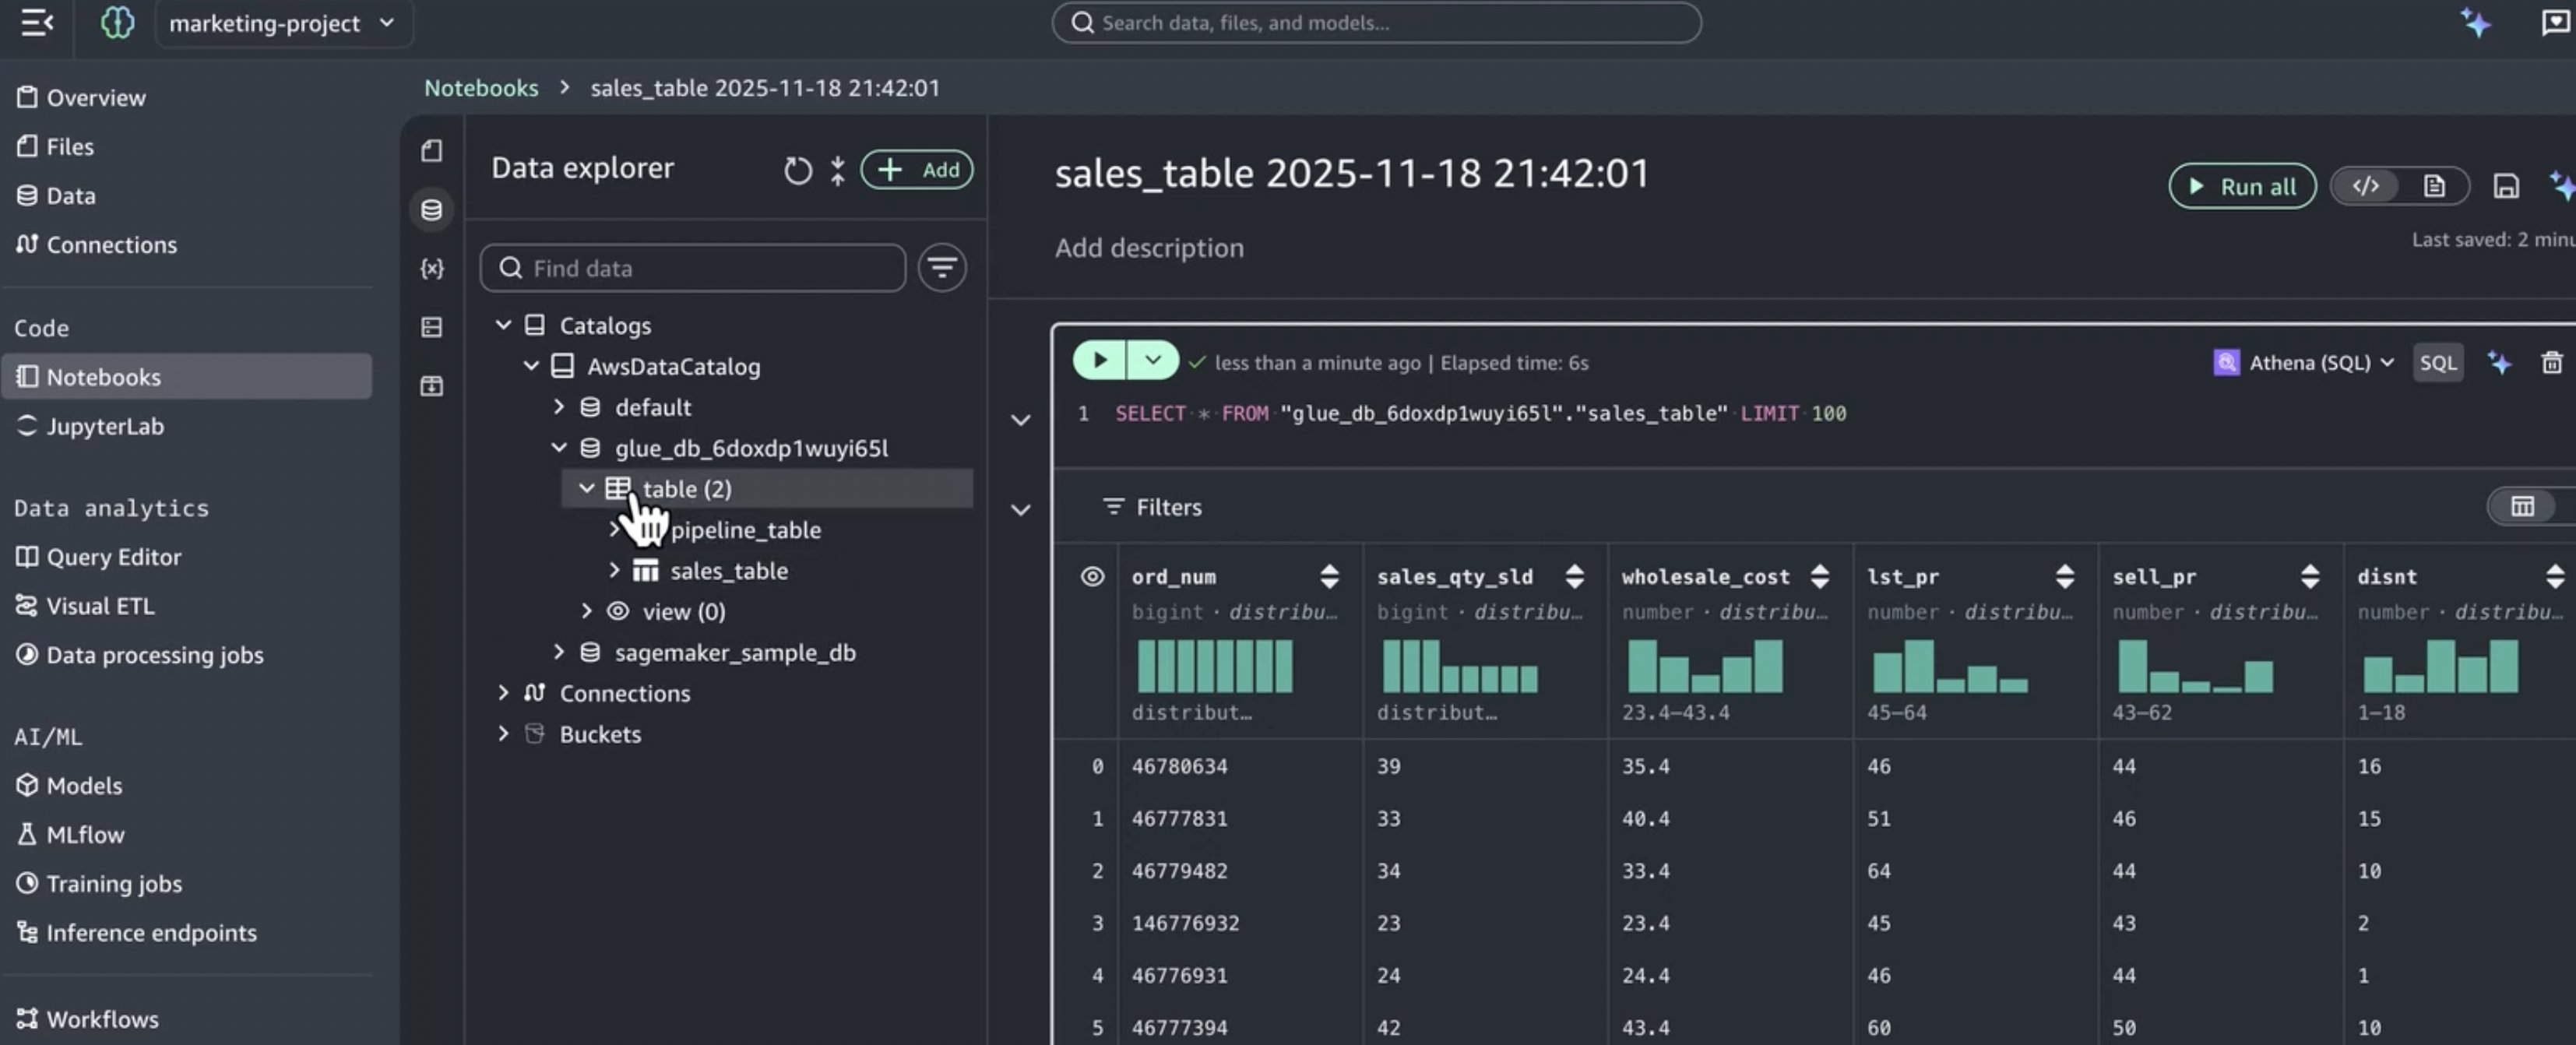
    1. In the Amazon SageMaker Unified Studio IAM-based domain project, navigate to the Data tab. If you created 2 projects with both option 1 and option 2 execution role, then 2 projects will show up and you can login to either to validate data access.

    Amazon SageMaker Unified Studio data explorer interface displaying SQL query "SELECT * FROM glue_db_6doxdp1wuy165l.sales_table LIMIT 100" executed via Athena in 6 seconds, showing six columns (ord_num, sales_qty_sld, wholesale_cost, lst_pr, sell_pr, disnt) with green distribution histograms above data preview table containing six sample sales records with order numbers ranging from 46776931 to 146776932, left navigation showing AwsDataCatalog database structure with glue_db_6doxdp1wuy165l containing pipeline_table and sales_table, last saved 2 minutes ago.

    1. Verify that the consumer database and subscribed tables appear.

    Create and use the new serverless notebooks

    With permissions properly configured, you can now use IAM-based domain capabilities like serverless Notebooks. Complete the following steps:

    1. In the Amazon SageMaker Unified Studio IAM-based domain project, select a table from the Data tab.
    2. Choose Create notebook.
    3. The Notebook opens with Athena SQL as the default cell type.
    4. Write and run queries against your subscribed data.

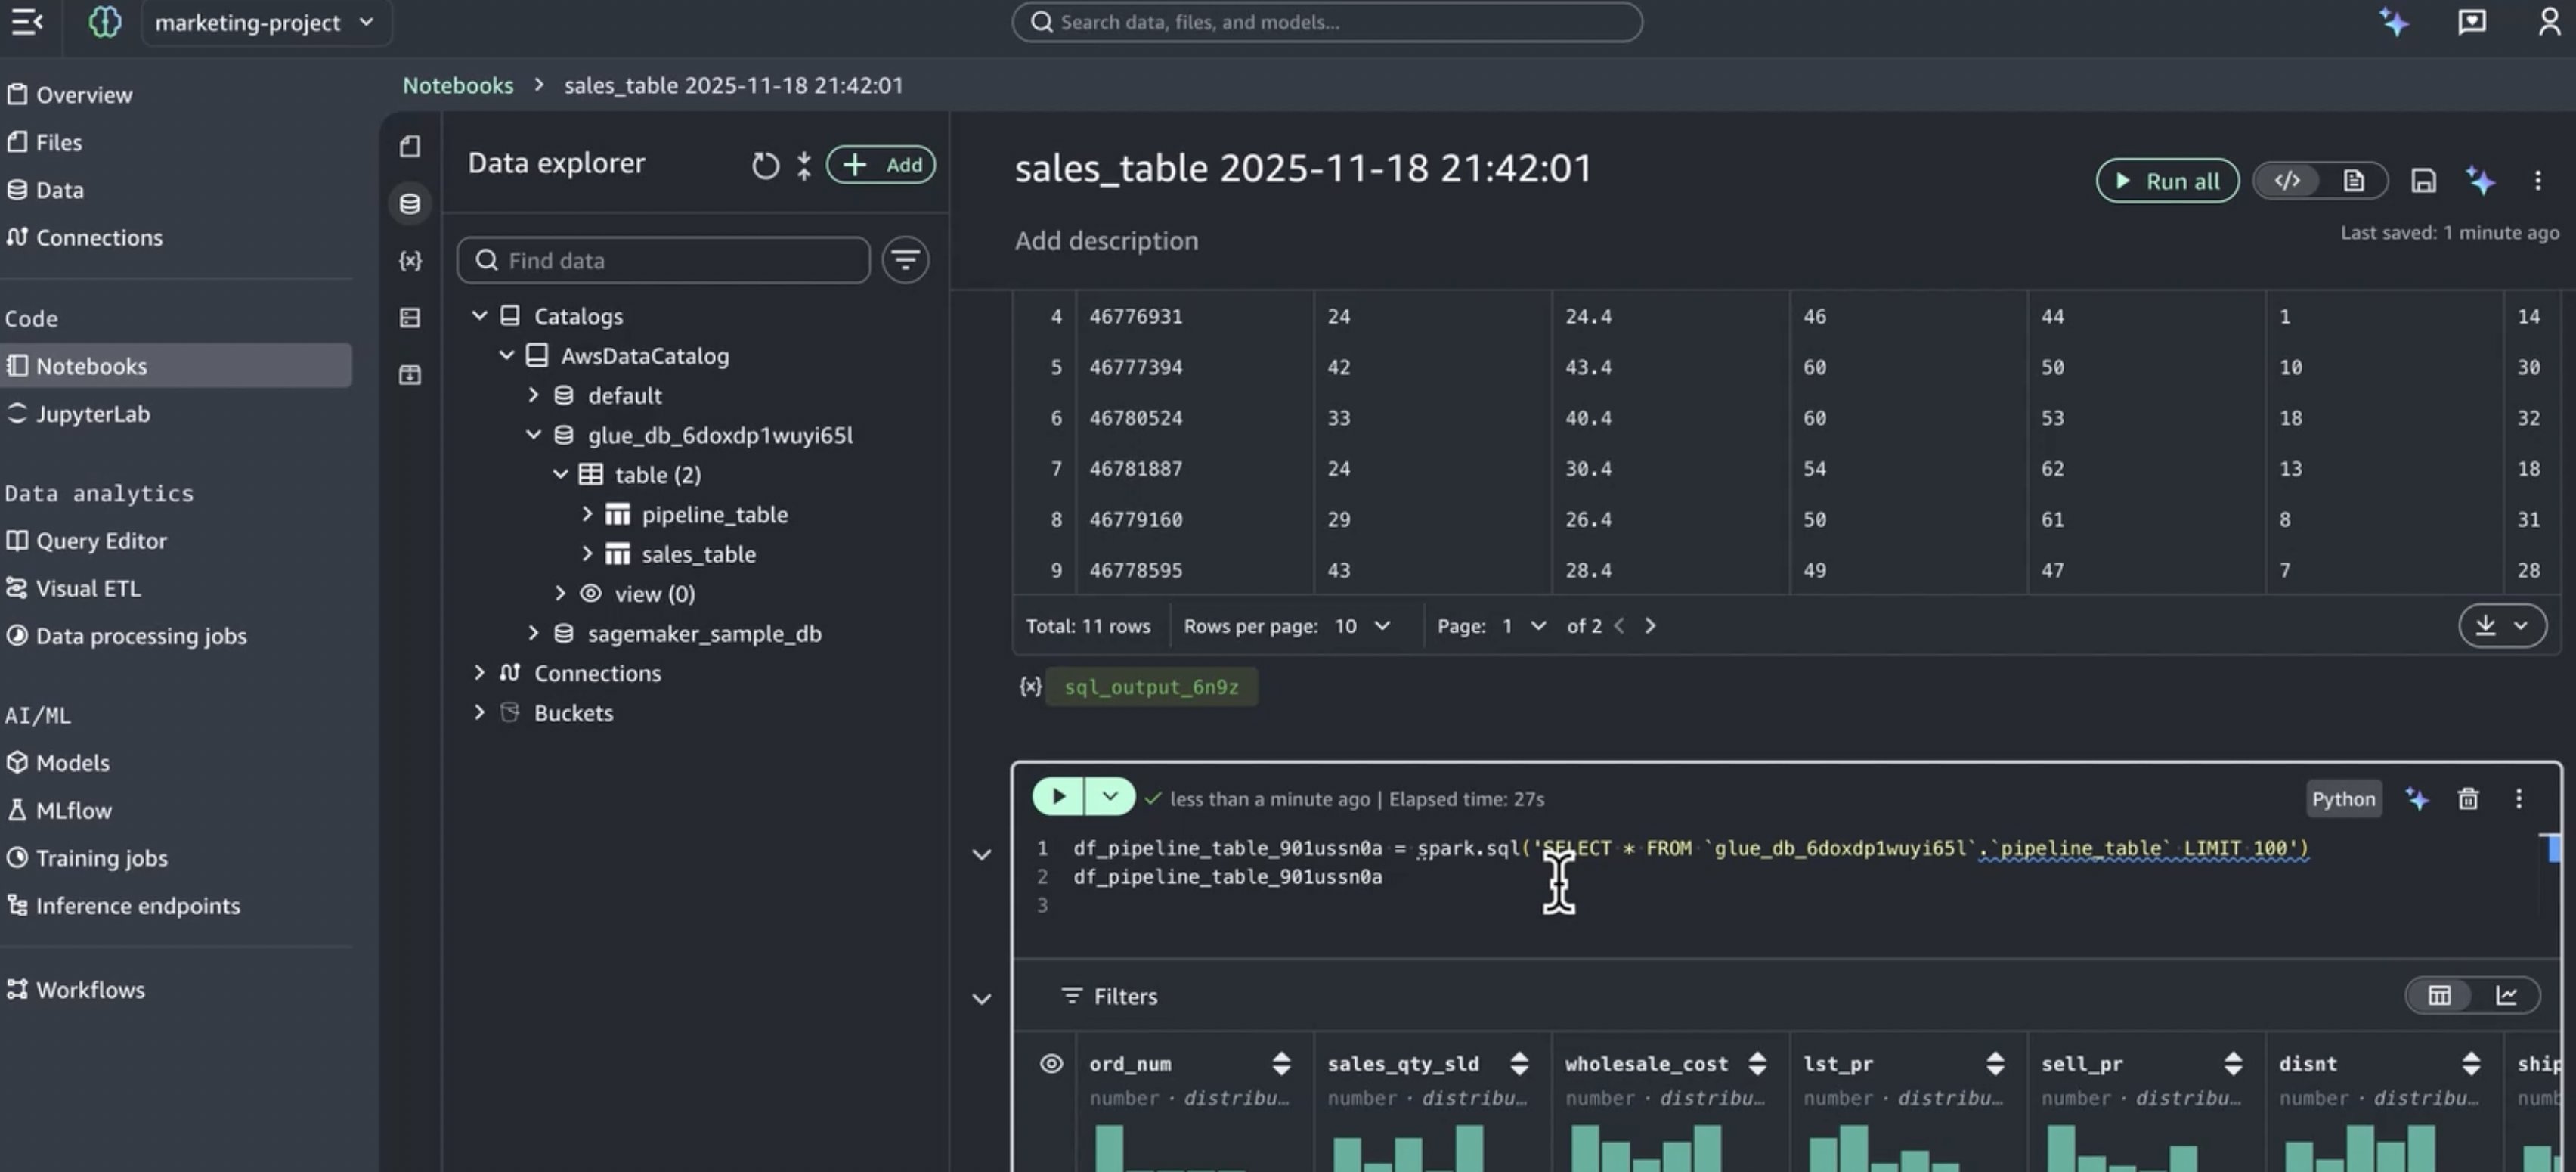
    Amazon SageMaker Unified Studio marketing-project notebook displaying sales_table data from 2025-11-18 21:42:01, left Data explorer showing AwsDataCatalog with glue_db_6doxdp1wuyi65l database containing pipeline_table and sales_table, main data table showing 11 rows with columns (ord_num, sales_qty_sld, wholesale_cost, lst_pr, sell_pr, disnt) displaying rows 4-9 on page 1 of 2, Python PySpark SQL query "SELECT * FROM 'glue_db_6doxdp1wuyi65l'.'pipeline_table' LIMIT 100" executed in 27 seconds, and Filters section displaying distribution histograms for all numerical columns.

    The notebook runs with the execution role’s permissions, which now include access to all data subscribed through the IDC-based domain.

    Key benefits of this integration

    This integration approach delivers several important advantages:

    Preserve existing investments

    • Continue using IDC-based domain governance and catalogs.
    • Maintain established Pub/Sub workflows.
    • No migration required for existing data assets.

    Get modern capabilities

    • Provide developers with the new serverless Notebooks.
    • Access Athena Spark for advanced analytics.
    • Provides improved user experience and navigation.

    Simplified permission management

    • Single subscription workflow manages access across both domains.
    • Consistent data access via role reuse and attribute-based access control.
    • No duplicate access requests or approvals needed.

    Unified data experience

    • Developers access all subscribed data from one interface.
    • Consistent data catalog across domains.
    • Simplified onboarding for new team members.

    Cleanup

    Complete the following steps to delete the resources you created:

    1. Delete the serverless Notebooks created in the IAM-based domain projects.
    2. Delete the IAM-based domain projects (Marketing Consumer Project and Marketing Consumer Project 2).
    3. Remove the permission set assignment from marketing group in IAM Identity Center.
    4. Delete the Marketing-federated-role permission set in IAM Identity Center.
    5. Remove the tags (AmazonDatazoneProject) from the execution role (if using Option 2).
    6. Delete the execution role created for the IAM-based domain (if using Option 2 and not reusing the IDC-based domain project role).
    7. Revert any policy changes made to the IDC-based domain consumer project IAM role (if using Option 1).
    8. If you do not need the IAM-based domain anymore, delete it.
    9. If you created any test data subscriptions in the IDC-based domain, remove them.

    Conclusion

    In this post, we demonstrated how to access Amazon SageMaker Unified Studio IDC-based domain with the new IAM-based domain using role reuse and attribute-based access control. This setup offers data engineers the best of both worlds: access to specialized modern development tools—including the new serverless Notebooks, Athena Spark integration, and built-in AI assistance , while maintaining proper governance that includes comprehensive catalog management and robust security controls established in the IDC-based domain.You can now confidently adopt Amazon SageMaker Unified Studio IAM-based domain capabilities knowing their established data governance, subscription workflows, and access controls remain intact and continue to function as expected.

    Ready to get started with Amazon SageMaker Unified Studio and unlock the power of integrated governance and modern development tools for your organization? Visit the Amazon SageMaker Unified Studio documentation to learn more and begin your implementation today.


    About the authors

    Praveen Kumar

    Praveen Kumar

    Praveen is a Principal Analytics Solutions Architect at AWS with expertise in designing, building, and implementing modern data and analytics platforms using cloud-based services. His areas of interest are serverless technology, data governance, and data-driven AI applications.

    Durga Mishra

    Durga Mishra

    Durga is a Principal Data and AI solutions architecture strategist at AWS . Outside of work, Durga enjoys building new things and spending time with family. He loves to hike on Appalachian trails and spend time in nature.

    Joel

    Joel Farvault

    Joel is a Principal Specialist SA Analytics for AWS with 25 years’ experience working on enterprise architecture, data governance and analytics. He uses his experience to advise customers on their data strategy and technology foundations.

    author name

    Satish Sarapuri

    Satish is a Sr. Data Architect for Data Mesh/Data Lake/Gen AI at AWS. He helps enterprise-level customers build generative AI, data mesh, data lake, and analytics platform solutions on AWS to help them make data-driven decisions and gain impactful outcomes for their business. In his spare time, he enjoys trail running and spending quality time with his family.

    author name

    Leonardo Gomez

    Leonardo is a Principal Analytics Specialist Solutions Architect at AWS. He has over a decade of experience in data management, helping customers around the globe address their business and technical needs.

    Author visual ETL flows on Amazon SageMaker Unified Studio (preview)

    Post Syndicated from Praveen Kumar original https://aws.amazon.com/blogs/big-data/author-visual-etl-flows-on-amazon-sagemaker-unified-studio/

    Amazon SageMaker Unified Studio (preview) provides an integrated data and AI development environment within Amazon SageMaker. From the Unified Studio, you can collaborate and build faster using familiar AWS tools for model development, generative AI, data processing, and SQL analytics. This experience includes visual ETL, a new visual interface that makes it simple for data engineers to author, run, and monitor extract, transform, load (ETL) data integration flow. You can use a simple visual interface to compose flows that move and transform data and run them on serverless compute. Additionally, you can choose to author your visual flows with English using generative AI prompts powered by Amazon Q. Visual ETL also automatically converts your visual flow directed acyclic graph (DAG) into Spark native scripts so you can continue authoring by notebook, enabling a quick-start experience for developers who prefer to author using code.

    This post shows how you can build a low-code and no-code (LCNC) visual ETL flow that enables seamless data ingestion and transformation across multiple data sources. We demonstrate how to:

    Additionally, we explore how generative AI can enhance your LCNC visual ETL development process, creating an intuitive and powerful workflow that streamlines the entire development experience.

    Use case walkthrough

    In this example, we use Amazon SageMaker Unified Studio to develop a visual ETL flow. This pipeline reads data from an Amazon S3 based file location, performs transformations on the data, and subsequently writes the transformed data back into an Amazon S3 based AWS Glue Data Catalog table. We use allevents_pipe and venue_pipe files from the TICKIT dataset to demonstrate this capability.

    The TICKIT dataset records sales activities on the fictional TICKIT website, where users can purchase and sell tickets online for different types of events such as sports games, shows, and concerts. Analysts can use this dataset to track how ticket sales change over time, evaluate the performance of sellers, and determine the most successful events, venues, and seasons in terms of ticket sales.

    The process involves merging the allevents_pipe and venue_pipe files from the TICKIT dataset. Next, the merged data is filtered to include only a specific geographic region. The data is then aggregated to calculate the number of events by venue name. In the end, the transformed output data is saved to Amazon S3, and a new AWS Glue Data Catalog table is created.

    The following diagram illustrates the architecture:

    Prerequisites

    To run the instruction, you must complete the following prerequisites:

    • An AWS account
    • A SageMaker Unified Studio domain
    • A SageMaker Unified Studio project with Data analytics and machine learning project profile

    Build a visual ETL flow

    Complete following steps to build a new visual ETL flow with sample dataset:

    1. On the SageMaker Unified Studio console, on the top menu, choose Build.
    2. Under DATA ANALYSIS & INTEGRATION, choose Visual ETL flows, as shown in the following screenshot.

    1. Select your project and choose Continue.

    1. Choose Create visual ETL flow.

    This time, manually define the ETL flow.

    1. On the top left, choose the + icon in the circle. Under Data sources, choose Amazon S3, as shown in the following screenshot. Locate the icon at the canvas.

    1. Choose the Amazon S3 source node and enter the following values:
      • S3 URI: s3://aws-blogs-artifacts-public/artifacts/BDB-4798/data/venue.csv
      • Format: CSV
      • Delimiter: ,
      • Multiline: Enabled
      • Header: Disabled

    Leave the rest as default.

    1. Wait for the data preview to be available at the bottom of the screen.

    1. Choose the + icon in the circle to the right of the Amazon S3 node. Under Transforms, choose Rename Columns.

    1. Choose the Rename Columns node and choose Add new rename pair. For Current name and New name, enter the following pairs:
      • _c0: venueid
      • _c1venuename
      • _c2venuecity
      • _c3venuestate
      • _c4venueseats

    1. Choose the + icon to the right of Rename Columns node. Under Transforms, choose Filter.
    2. Choose Add new filter condition.
    3. For Key, choose venuestate. For Operation, choose ==. For Value, enter DC, as shown in the following screenshot.

    1. Repeat steps 5 and 6 to add the Amazon S3 source node for table events.
      • S3 URI: s3://aws-blogs-artifacts-public/artifacts/BDB-4798/data/events.csv
      • Format: CSV
      • Sep: ,
      • Multiline: Enabled
      • Header: Disabled

    Leave the rest as default

    1. Repeat steps 7 and 8 for the Amazon S3 source node. On the Rename Columns node, choose Add new rename pair. For Current name and New name, enter the following pairs:
      • _c0: eventid
      • _c1e_venueid
      • _c2catid
      • _c3dateid
      • _c4eventname
      • _c5starttime

    1. Choose the + icon to the right of Rename Column node. Under Transforms, choose Join.
    2. Drag the + icon at the right of the Filter node and drop it at the left of the Join node.
    3. For Join type, choose Inner. For Left data source, choose e_venueid. For Right data source, choose venue_id.

    1. Choose the + icon to the right of the Join node. Under Transforms, choose SQL Query.
    2. Enter the following query statement:
    select 
      venuename,
      count(distinct eventid) as eventid_count 
    from {myDataSource} 
    group by venuename

    1. Choose the + icon to the right of the SQL Query node. Under Data target, choose Amazon S3.
    2. Choose the Amazon S3 target node and enter the following values:
      • S3 URI: <choose s3 location from project overview page and add suffix “/output/venue_event/”> (for example, s3://<bucket-name>/dzd_bd693kieeb65yf/52d3z1nutb42w7/dev/output/venue_event/)
      • Format: Parquet
      • Compression: Snappy
      • Mode: Overwrite
      • Update catalog: True
      • Database: Choose your database
      • Table: venue_event_agg

    At this point, you should encounter this end-to-end visual flow. Now you can publish it.

    1. On the top right, choose Save to project to save the draft flow. You can optionally change the name and add a description. Choose Save to project, as shown in the following screenshot.

    The visual ETL flow has been successfully saved.

    Run flow

    This section shows you how to run the visual ETL flow you authored.

    1. On the top right, choose Run.

    At the bottom of the screen, the run status is shown. The run status transitions from Starting to Running and Running to Finished.

    1. Wait for the run to be Finished.

    Query using Amazon Athena

    The output data has been written to the target S3 bucket. This section shows you how to query the output table.

    1. On the top left menu, under DATA ANALYSIS & INTEGRATION, choose Query Editor.

    1. On the data explorer, under Lakehouse, choose AwsDataCatalog. Navigate to the table venue_event_agg.
    2. From the three dots icon, choose Query with Athena.

    Four records will be returned, as shown in the following screenshot. This indicates you succeeded in querying the output table written by the visual ETL flow.

    Generative AI section to generate a visual ETL flow

    The preceding instruction is done in step-by-step operations on the visual console. On the other hand, SageMaker Unified Studio can automate job authoring steps by using generative AI powered by Amazon Q.

    1. On the top left menu, choose Visual ETL flows.
    2. Choose Create visual ETL flow.
    3. Enter the following text and choose Submit.

    Create a flow to connect 2 Glue catalog tables venue and event in database glue_db, join on event id , filter on venue state with condition as venuestate=='DC' and write output to a S3 location

    This creates the following boilerplate flow that you can edit to quickly author the visual ETL flow.

    The generated flow keeps the context of the prompt at the node level.

    Clean Up

    To avoid incurring future charges, clean up the resources you created during this walkthrough:

    1. From the SQL querybook, enter the following SQL to drop table:
    drop table venue_event_agg
    1. To delete the flow, under Actions, choose Delete flow

    Conclusion

    This post demonstrated how you can use Amazon SageMaker Unified Studio to build a low-code no-code (LCNC) visual ETL flow. This allows for a seamless data ingestion and transformation across multiple data sources.

    To learn more, refer to our documentation and the AWS News Blog.


    About the Authors

    praveenPraveen Kumar is an Analytics Solutions Architect at AWS with expertise in designing, building, and implementing modern data and analytics platforms using cloud-based services. His areas of interest are serverless technology, data governance, and data-driven AI applications.

    noriNoritaka Sekiyama is a Principal Big Data Architect with AWS Analytics services. He is responsible for building software artifacts to help customers. In his spare time, he enjoys cycling on his road bike.

    alexandraAlexandra Tello is a Senior Front End Engineer with the AWS Analytics services in New York City. She is a passionate advocate for usability and accessibility. In her free time, she’s an espresso enthusiast and enjoys building mechanical keyboards.

    ranuRanu Shah is a Software Development Manager with AWS Analytics services. She loves building data analytics features for customers. Outside work, she enjoys reading books or listening to music.

    Gal blog picGal Heyne is a Technical Product Manager for AWS Analytics services with a strong focus on AI/ML and data engineering. She is passionate about developing a deep understanding of customers’ business needs and collaborating with engineers to design simple-to-use data products.

    Implement tag-based access control for your data lake and Amazon Redshift data sharing with AWS Lake Formation

    Post Syndicated from Praveen Kumar original https://aws.amazon.com/blogs/big-data/implement-tag-based-access-control-for-your-data-lake-and-amazon-redshift-data-sharing-with-aws-lake-formation/

    Data-driven organizations treat data as an asset and use it across different lines of business (LOBs) to drive timely insights and better business decisions. Many organizations have a distributed tools and infrastructure across various business units. This leads to having data across many instances of data warehouses and data lakes using a modern data architecture in separate AWS accounts.

    Amazon Redshift data sharing allows you to securely share live, transactionally consistent data in one Amazon Redshift data warehouse with another Redshift data warehouse within the same AWS account, across accounts, and across Regions, without needing to copy or move data from one cluster to another. Customers want to be able to manage their permissions in a central place across all of their assets. Previously, the management of Redshift datashares was limited to only within Amazon Redshift, which made it difficult to manage your data lake permissions and Amazon Redshift permissions in a single place. For example, you had to navigate to an individual account to view and manage access information for Amazon Redshift and the data lake on Amazon Simple Storage Service (Amazon S3). As an organization grows, administrators want a mechanism to effectively and centrally manage data sharing across data lakes and data warehouses for governance and auditing, and to enforce fine-grained access control.

    We recently announced the integration of Amazon Redshift data sharing with AWS Lake Formation. With this feature, Amazon Redshift customers can now manage sharing, apply access policies centrally, and effectively scale the permission using LF-Tags.

    Lake Formation has been a popular choice for centrally governing data lakes backed by Amazon S3. Now, with Lake Formation support for Amazon Redshift data sharing, it opens up new design patterns and broadens governance and security posture across data warehouses. With this integration, you can use Lake Formation to define fine-grained access control on tables and views being shared with Amazon Redshift data sharing for federated AWS Identity and Access Management (IAM) users and IAM roles. Lake Formation also provides tag-based access control (TBAC), which can be used to simplify and scale governance of data catalog objects such as databases and tables.

    In this post, we discuss this new feature and how to implement TBAC for your data lake and Amazon Redshift data sharing on Lake Formation.

    Solution overview

    Lake Formation tag-based access control (LF-TBAC) allows you to group similar AWS Glue Data Catalog resources together and define the grant or revoke permissions policy by using an LF-Tag expression. LF-Tags are hierarchical in that when a database is tagged with an LF-Tag, all tables in that database inherit the tag, and when a LF-Tag is applied to a table, all the columns within that table inherit the tag. Inherited tags then can be overridden if needed. You then can create access policies within Lake Formation using LF-Tag expressions to grant principals access to tagged resources using an LF-Tag expression. See Managing LF-Tags for metadata access control for more details.

    To demonstrate LF-TBAC with central data access governance capability, we use the scenario where two separate business units own particular datasets and need to share data across teams.

    We have a customer care team who manages and owns the customer information database including customer demographics data. And have a marketing team who owns a customer leads dataset, which includes information on prospective customers and contact leads.

    To be able to run effective campaigns, the marketing team needs access to the customer data. In this post, we demonstrate the process of sharing this data that is stored in the data warehouse and giving the marketing team access. Furthermore, there are personally identifiable information (PII) columns within the customer dataset that should only be accessed by a subset of power users on a need-to-know basis. This way, data analysts within marketing can only see non-PII columns to be able to run anonymous customer segment analysis, but a group of power users can access PII columns (for example, customer email address) to be able to run campaigns or surveys for specific groups of customers.

    The following diagram shows the structure of the datasets that we work with in this post and a tagging strategy to provide fine-grained column-level access.

    Beyond our tagging strategy on the data resources, the following table gives an overview of how we should grant permissions to our two personas via tags.

    IAM Role Persona Resource Type Permission LF-Tag expression
    marketing-analyst A data analyst in the marketing team DB describe (department:marketing OR department:customer) AND classification:private
    . Table select (department:marketing OR department:customer) AND classification:private
    . . . . .
    marketing-poweruser A privileged user in the marketing team DB describe (department:marketing OR department:customer) AND classification: private
    . Table (Column) select (department:marketing OR department:customer) AND (classification:private OR classification:pii-sensitive)

    The following diagram gives a high-level overview of the setup that we deploy in this post.

    The following is a high-level overview of how to use Lake Formation to control datashare permissions:

    Producer Setup:

    1. In the producers AWS account, the Amazon Redshift administrator that owns the customer database creates a Redshift datashare on the producer cluster and grants usage to the AWS Glue Data Catalog in the same account.
    2. The producer cluster administrator authorizes the Lake Formation account to access the datashare.
    3. In Lake Formation, the Lake Formation administrator discovers and registers the datashares. They must discover the AWS Glue ARNs they have access to and associate the datashares with an AWS Glue Data Catalog ARN. If you’re using the AWS Command Line Interface (AWS CLI), you can discover and accept datashares with the Redshift CLI operations describe-data-shares and associate-data-share-consumer. To register a datashare, use the Lake Formation CLI operation register-resource.
    4. The Lake Formation administrator creates a federated database in the AWS Glue Data Catalog; assigns tags to the databases, tables, and columns; and configures Lake Formation permissions to control user access to objects within the datashare. For more information about federated databases in AWS Glue, see Managing permissions for data in an Amazon Redshift datashare.

    Consumer Setup:

    1. On the consumer side (marketing), the Amazon Redshift administrator discovers the AWS Glue database ARNs they have access to, creates an external database in the Redshift consumer cluster using an AWS Glue database ARN, and grants usage to database users authenticated with IAM credentials to start querying the Redshift database.
    2. Database users can use the views SVV_EXTERNAL_TABLES and SVV_EXTERNAL_COLUMNS to find all the tables or columns within the AWS Glue database that they have access to; then they can query the AWS Glue database’s tables.

    When the producer cluster administrator decides to no longer share the data with the consumer cluster, the producer cluster administrator can revoke usage, deauthorize, or delete the datashare from Amazon Redshift. The associated permissions and objects in Lake Formation are not automatically deleted.

    Prerequisites:

    To follow the steps in this post, you must satisfy the following prerequisites:

    Deploy environment including producer and consumer Redshift clusters

    To follow along the steps outlined in this post, deploy following AWS CloudFormation stack that includes necessary resources to demonstrate the subject of this post:

    1. Choose Launch stack to deploy a CloudFormation template.
    2. Provide an IAM role that you have already configured as a Lake Formation administrator.
    3. Complete the steps to deploy the template and leave all settings as default.
    4. Select I acknowledge that AWS CloudFormation might create IAM resources, then choose Submit.

    This CloudFormation stack creates the following resources:

    • Producer Redshift cluster – Owned by the customer care team and has customer and demographic data on it.
    • Consumer Redshift cluster – Owned by the marketing team and is used to analyze data across data warehouses and data lakes.
    • S3 data lake – Contains the web activity and leads datasets.
    • Other necessary resources to demonstrate the process of sharing data – For example, IAM roles, Lake Formation configuration, and more. For a full list of resources created by the stack, examine the CloudFormation template.

    After you deploy this CloudFormation template, resources created will incur cost to your AWS account. At the end of the process, make sure that you clean up resources to avoid unnecessary charges.

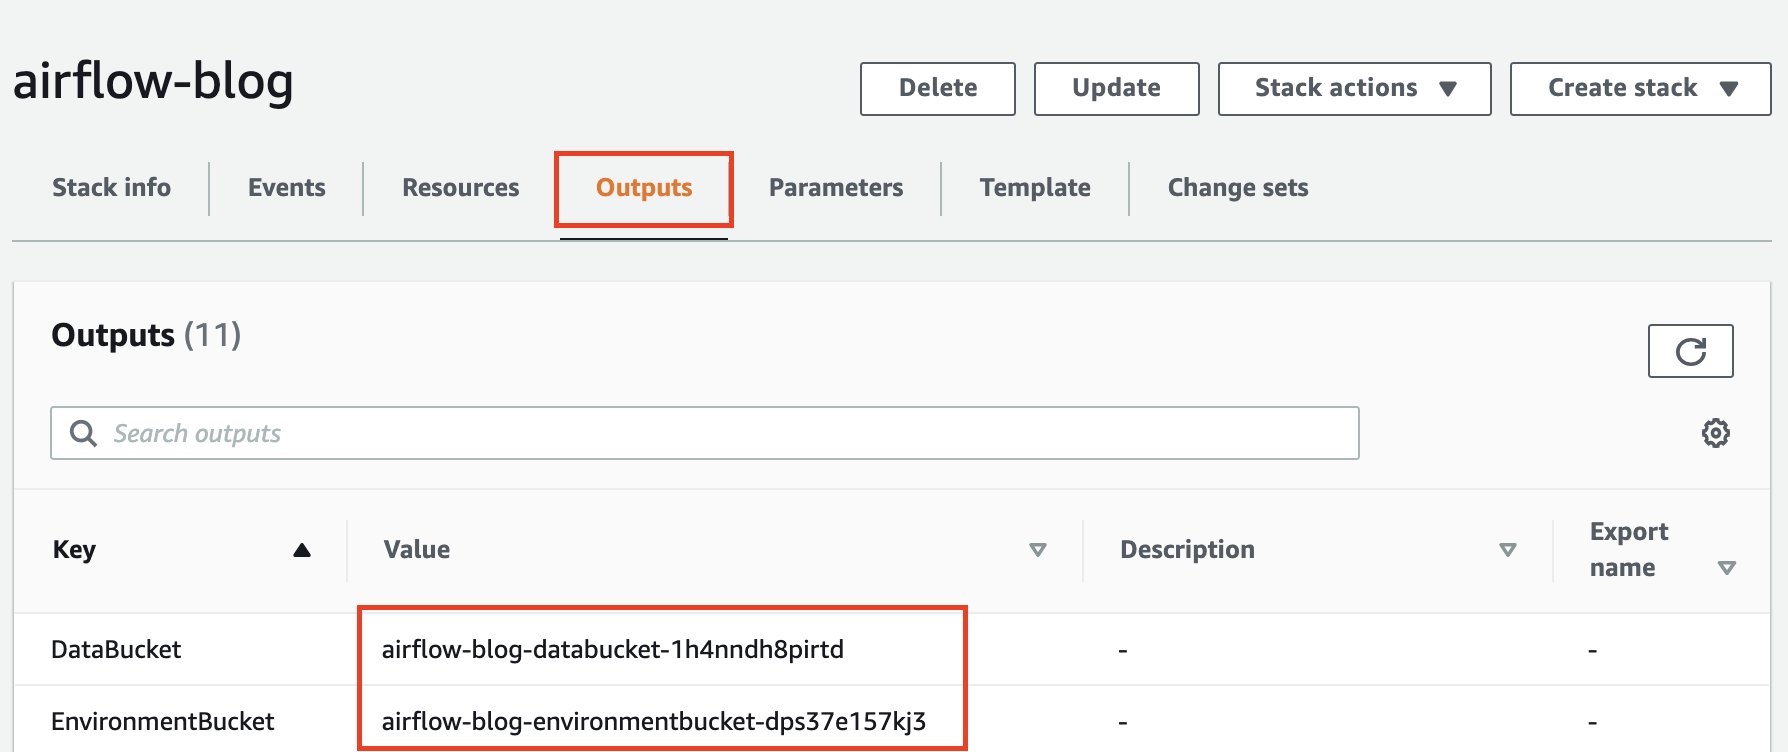
    After the CloudFormation stack is deployed successfully (status shows as CREATE_COMPLETE), take note of the following items on the Outputs tab:

    • Marketing analyst role ARN
    • Marketing power user role ARN
    • URL for Amazon Redshift admin password stored in AWS Secrets Manager

    Create a Redshift datashare and add relevant tables

    On the AWS Management Console, switch to the role that you nominated as Lake Formation admin when deploying the CloudFormation template. Then go to Query Editor v2. If this is the first time using Query Editor V2 in your account, follow these steps to configure your AWS account.

    The first step in Query Editor is to log in to the customer Redshift cluster using the database admin credentials to make your IAM admin role a DB admin on the database.

    1. Choose the options menu (three dots) next to the lfunified-customer-dwh cluster and choose Create connection.

    2. Select Database user name and password.
    3. Leave Database as dev.
    4. For User name, enter admin.
    5. For Password, complete the following steps:
      1. Go to the console URL, which is the value of the RedShiftClusterPassword CloudFormation output in previous step. The URL is the Secrets Manager console for this password.
      2. Scroll down to the Secret value section and choose Retrieve secret value.
      3. Take note of the password to use later when connecting to the marketing Redshift cluster.
      4. Enter this value for Password.
    6. Choose Create connection.

    Create a datashare using a SQL command

    Complete the following steps to create a datashare in the data producer cluster (customer care) and share it with Lake Formation:

    1. On the Amazon Redshift console, in the navigation pane, choose Editor, then Query editor V2.
    2. Choose (right-click) the cluster name and choose Edit connection or Create connection.
    3. For Authentication, select Temporary credentials using your IAM identity.

    Refer to Connecting to an Amazon Redshift database to learn more about the various authentication methods.

    1. For Database, enter a database name (for this post, dev).
    2. Choose Create connection to connect to the database.
    3. Run the following SQL commands to create the datashare and add the data objects to be shared:
      create datashare customer_ds;
      ALTER DATASHARE customer_ds ADD SCHEMA PUBLIC;
      ALTER DATASHARE customer_ds ADD TABLE customer;

    4. Run the following SQL command to share the customer datashare to the current account via the AWS Glue Data Catalog:
      GRANT USAGE ON DATASHARE customer_ds TO ACCOUNT '<aws-account-id>' via DATA CATALOG;

    5. Verify the datashare was created and objects shared by running the following SQL command:
      DESC DATASHARE customer_ds;

    Take note of the datashare producer cluster name space and account ID, which will be used in the following step. You can complete the following actions on the console, but for simplicity, we use AWS CLI commands.

    1. Go to CloudShell or your AWS CLI and run the following AWS CLI command to authorize the datashare to the Data Catalog so that Lake Formation can manage them:
      aws redshift authorize-data-share \
      --data-share-arn 'arn:aws:redshift:<aws-region>:<aws-account-id>:datashare:<producer-cluster-namespace>/customer_ds' \
      --consumer-identifier DataCatalog/<aws-account-id>

    The following is an example output:

     {
        "DataShareArn": "arn:aws:redshift:us-east-2:<aws-account-id>:datashare:cd8d91b5-0c17-4567-a52a-59f1bdda71cd/customer_ds",
        "ProducerArn": "arn:aws:redshift:us-east-2:<aws-account-id>:namespace:cd8d91b5-0c17-4567-a52a-59f1bdda71cd",
        "AllowPubliclyAccessibleConsumers": false,
        "DataShareAssociations": [{
            "ConsumerIdentifier": "DataCatalog/<aws-account-id>XX",
            "Status": "AUTHORIZED",
            "CreatedDate": "2022-11-09T21:10:30.507000+00:00",
            "StatusChangeDate": "2022-11-09T21:10:50.932000+00:00"
        }]
    }

    Take note of your datashare ARN that you used in this command to use in the next steps.

    Accept the datashare in the Lake Formation catalog

    To accept the datashare, complete the following steps:

    1. Run the following AWS CLI command to accept and associate the Amazon Redshift datashare to the AWS Glue Data Catalog:
      aws redshift associate-data-share-consumer --data-share-arn 'arn:aws:redshift:<aws-region>:<aws-account-id>:datashare:<producer-cluster-namespace>/customer_ds' \
      --consumer-arn arn:aws:glue:<aws-region>:<aws-account-id>:catalog

    The following is an example output:

    {
     "DataShareArn": "arn:aws:redshift:us-east-2:<aws-account-id>:datashare:cfd5fcbd-3492-42b5-9507-dad5d87f7427/customer_ds",
     "ProducerArn": "arn:aws:redshift:us-east-2:<aws-account-id>:namespace:cfd5fcbd-3492-42b5-9507-dad5d87f7427",
     "AllowPubliclyAccessibleConsumers": false,
     "DataShareAssociations": [
     {
     "ConsumerIdentifier": "arn:aws:glue:us-east-2:<aws-account-id>:catalog",
     "Status": "ACTIVE",
     "ConsumerRegion": "us-east-2",
     "CreatedDate": "2023-05-18T12:25:11.178000+00:00",
     "StatusChangeDate": "2023-05-18T12:25:11.178000+00:00"
     }
     ]
    }
    1. Register the datashare in Lake Formation:
      aws lakeformation register-resource \
       --resource-arn arn:aws:redshift:<aws-region>:<producer-aws-account-id>:datashare:<producer-cluster-namespace>/customer_ds

    2. Create the AWS Glue database that points to the accepted Redshift datashare:
      aws glue create-database --region <aws-region> --cli-input-json '{
          "CatalogId": "<aws-account-id>",
          "DatabaseInput": {
              "Name": "customer_db_shared",
              "FederatedDatabase": {
                  "Identifier": "arn:aws:redshift:<aws-region>:<producer-aws-account-id>:datashare:<producer-cluster-namespace>/customer_ds",
                  "ConnectionName": "aws:redshift"
              }
          }
      }'

    3. To verify, go to the Lake Formation console and check that the database customer_db_shared is created.

    Now the data lake administrator can view and grant access on both the database and tables to the data consumer team (marketing) personas using Lake Formation TBAC.

    Assign Lake Formation tags to resources

    Before we grant appropriate access to the IAM principals of the data analyst and power user within the marketing team, we have to assign LF-tags to tables and columns of the customer_db_shared database. We then grant these principals permission to appropriate LF-tags.

    To assign LF-tags, follow these steps:

    1. Assign the department and classification LF-tag to customer_db_shared (Redshift datashare) based on the tagging strategy table in the solution overview. You can run the following actions on the console, but for this post, we use the following AWS CLI command:
      aws lakeformation add-lf-tags-to-resource --cli-input-json '{
          "CatalogId": "<aws-account-id>",
          "Resource": {
          "Database": {
          "CatalogId": "<aws-account-id>",
          "Name": "customer_db_shared"
          }
          },
          "LFTags": [
          {
          "CatalogId": "<aws-account-id>",
          "TagKey": "department",
          "TagValues": [
          "customer"]
          },
          {
          "CatalogId": "<aws-account-id>",
          "TagKey": "classification",
          "TagValues": [
          "private"]
          }
          ]
          }'

    If the command is successful, you should get a response like the following:

    {
    "Failures": []
    }
    1. Assign the appropriate department and classification LF-tag to marketing_db (on the S3 data lake):
      aws lakeformation add-lf-tags-to-resource --cli-input-json '{
          "CatalogId": "<aws-account-id>",
          "Resource": {
          "Database": {
          "CatalogId": "<aws-account-id>",
          "Name": "lfunified_marketing_dl_db"
          }
          },
          "LFTags": [
          {
          "CatalogId": "<aws-account-id>",
          "TagKey": "department",
          "TagValues": [
          "marketing"]
          },
          {
          "CatalogId": "<aws-account-id>",
          "TagKey": "classification",
          "TagValues": [
          "private"]
          }
          ]
          }'

    Note that although you only assign the department and classification tag on the database level, it gets inherited by the tables and columns within that database.

    1. Assign the classification pii-sensitive LF-tag to PII columns of the customer table to override the inherited value from the database level:
      aws lakeformation add-lf-tags-to-resource --cli-input-json '{
          "CatalogId": "<aws-account-id>",
          "Resource": {
          "TableWithColumns": {
          "CatalogId": "<aws-account-id>",
          "DatabaseName": "customer_db_shared",
          "Name": "public.customer",
          "ColumnNames":["c_first_name","c_last_name","c_email_address"]
          }
          },
          "LFTags": [
          {
          "CatalogId": "<aws-account-id>",
          "TagKey": "classification",
          "TagValues": [
          "pii-sensitive"]
          }
          ]
          }'

    Grant permission based on LF-tag association

    Run the following two AWS CLI commands to allow the marketing data analyst access to the customer table excluding the pii-sensitive (PII) columns. Replace the value for DataLakePrincipalIdentifier with the MarketingAnalystRoleARN that you noted from the outputs of the CloudFormation stack:

    aws lakeformation grant-permissions --cli-input-json '{
        "CatalogId": "<aws-account-id>",
        "Principal": {"DataLakePrincipalIdentifier" : "<MarketingAnalystRoleARN-from-CloudFormation-Outputs>"},
        "Resource": {
        "LFTagPolicy": {
        "CatalogId": "<aws-account-id>",
        "ResourceType": "DATABASE",
        "Expression": [{"TagKey": "department","TagValues": ["marketing","customer"]},{"TagKey": "classification","TagValues": ["private"]}]
        }
        },
        "Permissions": [
        "DESCRIBE"
        ],
        "PermissionsWithGrantOption": []
    }'
    aws lakeformation grant-permissions --cli-input-json '{
        "CatalogId": "<aws-account-id>",
        "Principal": {"DataLakePrincipalIdentifier" : "<MarketingAnalystRoleARN-from-CloudFormation-Outputs>"},
        "Resource": {
        "LFTagPolicy": {
        "CatalogId": "<aws-account-id>",
        "ResourceType": "TABLE",
        "Expression": [{"TagKey": "department","TagValues": ["marketing","customer"]},{"TagKey": "classification","TagValues": ["private"]}]
        }
        },
        "Permissions": [
        "SELECT"
        ],
        "PermissionsWithGrantOption": []
    }'

    We have now granted marketing analysts access to the customer database and tables that are not pii-sensitive.

    To allow marketing power users access to table columns with restricted LF-tag (PII columns), run the following AWS CLI command:

    aws lakeformation grant-permissions --cli-input-json '{
        "CatalogId": "<aws-account-id>",
        "Principal": {"DataLakePrincipalIdentifier" : "<MarketingPowerUserRoleARN-from-CloudFormation-Outputs>"},
        "Resource": {
        "LFTagPolicy": {
        "CatalogId": "<aws-account-id>",
        "ResourceType": "DATABASE",
        "Expression": [{"TagKey": "department","TagValues": ["marketing","customer"]},{"TagKey": "classification","TagValues": ["private"]}]
        }
        },
        "Permissions": [
        "DESCRIBE"
        ],
        "PermissionsWithGrantOption": []
    }'
    aws lakeformation grant-permissions --cli-input-json '{
        "CatalogId": "<aws-account-id>",
        "Principal": {"DataLakePrincipalIdentifier" : "<MarketingPowerUserRoleARN-from-CloudFormation-Outputs>"},
        "Resource": {
        "LFTagPolicy": {
        "CatalogId": "<aws-account-id>",
        "ResourceType": "TABLE",
        "Expression": [{"TagKey": "department","TagValues": ["marketing","customer"]},{"TagKey": "classification","TagValues": ["private", "pii-sensitive"]}]
        }
        },
        "Permissions": [
        "SELECT"
        ],
        "PermissionsWithGrantOption": []
    }'

    We can combine the grants into a single batch grant permissions call:

    aws lakeformation batch-grant-permissions --region us-east-1 --cli-input-json '{
        "CatalogId": "<aws-account-id>",
     "Entries": [
     {  "Id": "1",
        "Principal": {"DataLakePrincipalIdentifier" : "arn:aws:iam:: <aws-account-id>:role/Blog-MarketingAnalystRole-1CYV6JSNN14E3"},
        "Resource": {
        "LFTagPolicy": {
        "CatalogId": "<aws-account-id>",
        "ResourceType": "DATABASE",
        "Expression": [{"TagKey": "department","TagValues": ["marketing","customer"]},{"TagKey": "classification","TagValues": ["private"]}]
        }
        },
        "Permissions": [
        "DESCRIBE"
        ],
        "PermissionsWithGrantOption": []
        },
        {  "Id": "2",
        "Principal": {"DataLakePrincipalIdentifier" : "arn:aws:iam:: <aws-account-id>:role/Blog-MarketingAnalystRole-1CYV6JSNN14E3"},
        "Resource": {
        "LFTagPolicy": {
        "CatalogId": "<aws-account-id>",
        "ResourceType": "TABLE",
        "Expression": [{"TagKey": "department","TagValues": ["marketing","customer"]},{"TagKey": "classification","TagValues": ["private"]}]
        }
        },
        "Permissions": [
        "SELECT"
        ],
        "PermissionsWithGrantOption": []
        },
         {  "Id": "3",
        "Principal": {"DataLakePrincipalIdentifier" : "arn:aws:iam:: <aws-account-id>:role/Blog-MarketingPoweruserRole-RKKM0TWQBP0W"},
        "Resource": {
        "LFTagPolicy": {
        "CatalogId": "<aws-account-id>",
        "ResourceType": "DATABASE",
        "Expression": [{"TagKey": "department","TagValues": ["marketing","customer"]},{"TagKey": "classification","TagValues": ["private", "pii-sensitive"]}]
        }
        },
        "Permissions": [
        "DESCRIBE"
        ],
        "PermissionsWithGrantOption": []
        },
        {  "Id": "4",
        "Principal": {"DataLakePrincipalIdentifier" : "arn:aws:iam:: <aws-account-id>:role/Blog-MarketingPoweruserRole-RKKM0TWQBP0W"},
        "Resource": {
        "LFTagPolicy": {
        "CatalogId": "<aws-account-id>",
        "ResourceType": "TABLE",
        "Expression": [{"TagKey": "department","TagValues": ["marketing","customer"]},{"TagKey": "classification","TagValues": ["private", "pii-sensitive"]}]
        }
        },
        "Permissions": [
        "SELECT"
        ],
        "PermissionsWithGrantOption": []
        }
        ]
     }'

    Validate the solution

    In this section, we go through the steps to test the scenario.

    Consume the datashare in the consumer (marketing) data warehouse

    To enable the consumers (marketing team) to access the customer data shared with them via the datashare, first we have to configure Query Editor v2. This configuration is to use IAM credentials as the principal for the Lake Formation permissions. Complete the following steps:

    1. Sign in to the console using the admin role you nominated in running the CloudFormation template step.
    2. On the Amazon Redshift console, go to Query Editor v2.
    3. Choose the gear icon in the navigation pane, then choose Account settings.
    4. Under Connection settings, select Authenticate with IAM credentials.
    5. Choose Save.

    Now let’s connect to the marketing Redshift cluster and make the customer database available to the marketing team.

    1. Choose the options menu (three dots) next to the Serverless:lfunified-marketing-wg cluster and choose Create connection.
    2. Select Database user name and password.
    3. Leave Database as dev.
    4. For User name, enter admin.
    5. For Password, enter the same password you retrieved from Secrets Manger in an earlier step.
    6. Choose Create connection.
    7. Once successfully connected, choose the plus sign and choose Editor to open a new Query Editor tab.
    8. Make sure that you specify the Serverless: lfunified-marketing-wg workgroup and dev database.
    9. To create the Redshift database from the shared catalog database, run the following SQL command on the new tab:
      CREATE DATABASE ext_customerdb_shared FROM ARN 'arn:aws:glue:<aws-region>:<aws-account-id>:database/customer_db_shared' WITH DATA CATALOG SCHEMA "customer_db_shared"

    10. Run the following SQL commands to create and grant usage on the Redshift database to the IAM roles for the power users and data analyst. You can get the IAM role names from the CloudFormation stack outputs:
      CREATE USER IAMR:"lf-redshift-ds-MarketingAnalystRole-XXXXXXXXXXXX" password disable;
      GRANT USAGE ON DATABASE ext_customerdb_shared to IAMR:"lf-redshift-ds-MarketingAnalystRole-XXXXXXXXXXXX";
      
      CREATE USER IAMR:"lf-redshift-ds-MarketingPoweruserRole-YYYYYYYYYYYY" password disable;
      GRANT USAGE ON DATABASE ext_customerdb_shared to IAMR:"lf-redshift-ds-MarketingPoweruserRole-YYYYYYYYYYYY";

    Create the data lake schema in AWS Glue and allow the marketing power role to query the lead and web activity data

    Run the following SQL commands to make the lead data in the S3 data lake available to the marketing team:

    create external schema datalake from data catalog
    database 'lfunified_marketing_dl_db' 
    iam_role 'SESSION'
    catalog_id '<aws-account-id>';
    GRANT USAGE ON SCHEMA datalake TO IAMR:"lf-redshift-ds-MarketingAnalystRole-XXXXXXXXXXXX";
    GRANT USAGE ON SCHEMA datalake TO IAMR:"lf-redshift-ds-MarketingPoweruserRole-YYYYYYYYYYYY";

    Query the shared dataset as a marketing analyst user

    To validate that the marketing team analysts (IAM role marketing-analyst-role) have access to the shared database, perform the following steps:

    1. Sign in to the console (for convenience, you can use a different browser) and switch your role to lf-redshift-ds-MarketingAnalystRole-XXXXXXXXXXXX.
    2. On the Amazon Redshift console, go to Query Editor v2.
    3. To connect to the consumer cluster, choose the Serverless: lfunified-marketing-wg consumer data warehouse in the navigation pane.
    4. When prompted, for Authentication, select Federated user.
    5. For Database, enter the database name (for this post, dev).
    6. Choose Save.
    7. Once you’re connected to the database, you can validate the current logged-in user with the following SQL command:
      select current_user;

    8. To find the federated databases created on the consumer account, run the following SQL command:
      SHOW DATABASES FROM DATA CATALOG ACCOUNT '<aws-account-id>';

    9. To validate permissions for the marketing analyst role, run the following SQL command:
      select * from ext_customerdb_shared.public.customer limit 10;

    As you can see in the following screenshot, the marketing analyst is able to successfully access the customer data but only the non-PII attributes, which was our intention.

    1. Now let’s validate that the marketing analyst doesn’t have access to the PII columns of the same table:
      select c_customer_email from ext_customerdb_shared.public.customer limit 10;

    Query the shared datasets as a marketing power user

    To validate that the marketing power users (IAM role lf-redshift-ds-MarketingPoweruserRole-YYYYYYYYYYYY) have access to pii-sensetive columns in the shared database, perform the following steps:

    1. Sign in to the console (for convenience, you can use a different browser) and switch your role to lf-redshift-ds-MarketingPoweruserRole-YYYYYYYYYYYY.
    2. On the Amazon Redshift console, go to Query Editor v2.
    3. To connect to the consumer cluster, choose the Serverless: lfunified-marketing-wg consumer data warehouse in the navigation pane.
    4. When prompted, for Authentication, select Federated user.
    5. For Database, enter the database name (for this post, dev).
    6. Choose Save.
    7. Once you’re connected to the database, you can validate the current logged-in user with the following SQL command:
      select current_user;

    8. Now let’s validate that the marketing power role has access to the PII columns of the customer table:
      select c_customer_id, c_first_name, c_last_name,c_customer_email from customershareddb.public.customer limit 10;

    9. Validate that the power users within the marketing team can now run a query to combine data across different datasets that they have access to in order to run effective campaigns:
      SELECT
          emailaddress as emailAddress,  customer.c_first_name as firstName, customer.c_last_name as lastName, leadsource, contactnotes, usedpromo
      FROM
          "dev"."datalake"."lead" as lead
      JOIN ext_customerdb_shared.public.customer as customer
      ON lead.emailaddress = customer.c_email_address
      WHERE lead.donotreachout = 'false'

    Clean up

    After you complete the steps in this post, to clean up resources, delete the CloudFormation stack:

    1. On the AWS CloudFormation console, select the stack you deployed in the beginning of this post.
    2. Choose Delete and follow the prompts to delete the stack.

    Conclusion

    In this post, we showed how you can use Lake Formation tags and manage permissions for your data lake and Amazon Redshift data sharing using Lake Formation. Using Lake Formation LF-TBAC for data governance helps you manage your data lake and Amazon Redshift data sharing permissions at scale. Also, it enables data sharing across business units with fine-grained access control. Managing access to your data lake and Redshift datashares in a single place enables better governance, helping with data security and compliance.

    If you have questions or suggestions, submit them in the comments section.

    For more information on Lake Formation managed Amazon Redshift data sharing and tag-based access control, refer to Centrally manage access and permissions for Amazon Redshift data sharing with AWS Lake Formation and Easily manage your data lake at scale using AWS Lake Formation Tag-based access control.


    About the Authors

    Praveen Kumar is an Analytics Solution Architect at AWS with expertise in designing, building, and implementing modern data and analytics platforms using cloud-native services. His areas of interests are serverless technology, modern cloud data warehouses, streaming, and ML applications.

    Srividya Parthasarathy is a Senior Big Data Architect on the AWS Lake Formation team. She enjoys building data mesh solutions and sharing them with the community.

    Paul Villena is an Analytics Solutions Architect in AWS with expertise in building modern data and analytics solutions to drive business value. He works with customers to help them harness the power of the cloud. His areas of interests are infrastructure as code, serverless technologies, and coding in Python.
    Mostafa Safipour is a Solutions Architect at AWS based out of Sydney. He works with customers to realize business outcomes using technology and AWS. Over the past decade, he has helped many large organizations in the ANZ region build their data, digital, and enterprise workloads on AWS.
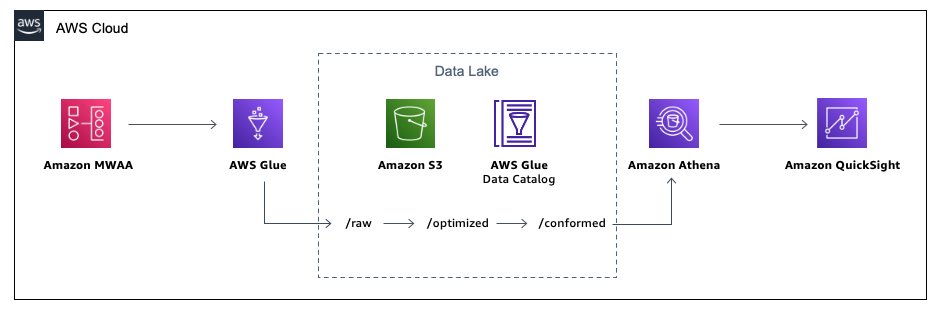
    Persist and analyze metadata in a transient Amazon MWAA environment

    Post Syndicated from Praveen Kumar original https://aws.amazon.com/blogs/big-data/persist-and-analyze-metadata-in-a-transient-amazon-mwaa-environment/

    Customers can harness sophisticated orchestration capabilities through the open-source tool Apache Airflow. Airflow can be installed on Amazon EC2 instances or can be dockerized and deployed as a container on AWS container services. Alternatively, customers can also opt to leverage Amazon Managed Workflows for Apache Airflow (MWAA).

    Amazon MWAA is a fully managed service that enables customers to focus more of their efforts on high-impact activities such as programmatically authoring data pipelines and workflows, as opposed to maintaining or scaling the underlying infrastructure. Amazon MWAA offers auto-scaling capabilities where it can respond to surges in demand by scaling the number of Airflow workers out and back in.

    With Amazon MWAA, there are no upfront commitments and you only pay for what you use based on instance uptime, additional auto-scaling capacity, and storage of the Airflow back-end metadata database. This database is provisioned and managed by Amazon MWAA and contains the necessary metadata to support the Airflow application.  It hosts key data points such as historical execution times for tasks and workflows and is valuable in understanding trends and behaviour of your data pipelines over time. Although the Airflow console does provide a series of visualisations that help you analyse these datasets, these are siloed from other Amazon MWAA environments you might have running, as well as the rest of your business data.

    Data platforms encompass multiple environments. Typically, non-production environments are not subject to the same orchestration demands and schedule as those of production environments. In most instances, these non-production environments are idle outside of business hours and can be spun down to realise further cost-efficiencies. Unfortunately, terminating Amazon MWAA instances results in the purging of that critical metadata.

    In this post, we discuss how to export, persist and analyse Airflow metadata in Amazon S3 enabling you to run and perform pipeline monitoring and analysis. In doing so, you can spin down Airflow instances without losing operational metadata.

    Benefits of Airflow metadata

    Persisting the metadata in the data lake enables customers to perform pipeline monitoring and analysis in a more meaningful manner:

    • Airflow operational logs can be joined and analysed across environments
    • Trend analysis can be conducted to explore how data pipelines are performing over time, what specific stages are taking the most time, and how is performance effected as data scales
    • Airflow operational data can be joined with business data for improved record level lineage and audit capabilities

    These insights can help customers understand the performance of their pipelines over time and guide focus towards which processes need to be optimised.

    The technique described below to extract metadata is applicable to any Airflow deployment type, but we will focus on Amazon MWAA in this blog.

    Solution Overview

    The below diagram illustrates the solution architecture. Please note, Amazon QuickSight is NOT included as part of the CloudFormation stack and is not covered in this tutorial. It has been placed in the diagram to illustrate that metadata can be visualised using a business intelligence tool.

    As part of this tutorial, you will be performing the below high-level tasks:

    • Run CloudFormation stack to create all necessary resources
    • Trigger Airflow DAGs to perform sample ETL workload and generate operational metadata in back-end database
    • Trigger Airflow DAG to export operational metadata into Amazon S3
    • Perform analysis with Amazon Athena

    This post comes with an AWS CloudFormation stack that automatically provisions the necessary AWS resources and infrastructure, including an active Amazon MWAA instance, for this solution. The entire code is available in the GitHub repository.

    The Amazon MWAA instance will already have three directed-acyclic graphs (DAGs) imported:

    1. glue-etl – This ETL workflow leverages AWS Glue to perform transformation logic on a CSV file (customer_activity.csv). This file will be loaded as part of the CloudFormation template into the s3://<DataBucket>/raw/ prefix.

    The first task glue_csv_to_parquet converts the ‘raw’ data to parquet format and stores the data in location s3://<DataBucket>/optimised/.  By converting the data in parquet format, you can achieve faster query performance and lower query costs.

    The second task glue_transform runs an aggregation over the newly created parquet format and stores the aggregated data in location s3://<DataBucket>/conformed/.

    1. db_export_dag – This DAG consists of one task, export_db, which exports the data from the back-end Airflow database into Amazon S3 in the location s3://<DataBucket>/export/.

    Please note that you may experience time-out issues when extracting large amounts of data. On busy Airflow instances, our recommendation will be to set up frequent extracts in small chunks.

    1. run-simple-dag – This DAG does not perform any data transformation or manipulation. It is used in this blog for the purposes of populating the back-end Airflow database with sufficient operational data.

    Prerequisites

    To implement the solution outlined in this blog, you will need following :

    Steps to run a data pipeline using Amazon MWAA and saving metadata to s3:

    1. Choose Launch Stack:
    2. Choose Next.
    3. For Stack name, enter a name for your stack.
    4. Choose Next.
    5. Keep the default settings on the ‘Configure stack options’ page, and choose Next.
    6. Acknowledge that the template may create AWS Identity and Access Management (IAM) resources.
    7. Choose Create stack. The stack can take up to 30 mins to complete.

    The CloudFormation template generates the following resources:

      • VPC infrastructure that uses Public routing over the Internet.
      • Amazon S3 buckets required to support Amazon MWAA, detailed below:
        • The Data Bucket, refered in this blog as s3://<DataBucket>, holds the data which will be optimised and transformed for further analytical consumption. This bucket will also hold the data from the Airflow back-end metadata database once extracted.
        • The Environment Bucket, refered in this blog as s3://<EnvironmentBucket>, stores your DAGs, as well as any custom plugins, and Python dependencies you may have.
      • Amazon MWAA environment that’s associated to the  s3://<EnvironmentBucket>/dags location.
      • AWS Glue jobs for data processing and help generate airflow metadata.
      • AWS Lambda-backed custom resources to upload to Amazon S3 the sample data, AWS Glue scripts and DAG configuration files,
      • AWS Identity and Access Management (IAM) users, roles, and policies.
    1. Once the stack creation is successful, navigate to the Outputs tab of the CloudFormation stack and make note of DataBucket and EnvironmentBucket name. Store your Apache Airflow Directed Acyclic Graphs (DAGs), custom plugins in a plugins.zip file, and Python dependencies in a requirements.txt file.
    2. Open the Environments page on the Amazon MWAA console.
    3. Choose the environment created above. (The environment name will include the stack name). Click on Open Airflow UI.
    4. Choose glue-etl DAG , unpause by clicking the radio button next to the name of the DAG and click on the Play Button on Right hand side to Trigger DAG. It may take up to a minute for DAG to appear.
    5. Leave Configuration JSON as empty and hit Trigger.
    6. Choose run-simple-dag DAG, unpause and click on Trigger DAG.
    7. Once both DAG executions have completed, select the db_export_dag DAG, unpause and click on Trigger DAG. Leave Configuration JSON as empty and hit Trigger.

    This step will extract the dag and task metadata to a S3 location. This is a sample list of tables and more tables can be added as required. The exported metadata will be located in s3://<DataBucket>/export/ folder.

    Visualise using Amazon QuickSight and Amazon Athena

    Amazon Athena is a serverless interactive query service that can be used to run exploratory analysis on data stored in Amazon S3.

    If you are using Amazon Athena for the first time, please find the steps here to setup query location. We can use Amazon Athena to explore and analyse the metadata generated from airflow dag runs.

    1. Navigate to Athena Console and click explore the query editor.
    2. Hit View Settings.
    3. Click Manage.
    4. Replace with s3://<DataBucket>/logs/athena/. Once completed, return to the query editor.
    5. Before we can perform our pipeline analysis, we need to create the below DDLs. Replace the <DataBucket> as part of the LOCATION clause with the parameter value as defined in the CloudFormation stack (noted in Step 8 above).
      CREATE EXTERNAL TABLE default.airflow_metadata_dagrun (
              sa_instance_state STRING,
              dag_id STRING,
              state STRING,
              start_date STRING,
              run_id STRING,
              external_trigger STRING,
              conf_name STRING,
              dag_hash STRING,
               id STRING,
              execution_date STRING,
              end_date STRING,
              creating_job_id STRING,
              run_type STRING,
              last_scheduling_decision STRING
         )
      PARTITIONED BY (dt string)
      ROW FORMAT DELIMITED
      FIELDS TERMINATED BY ','
      LOCATION 's3://<DataBucket>/export/dagrun/'
      TBLPROPERTIES ("skip.header.line.count"="1");
      MSCK REPAIR TABLE default.airflow_metadata_dagrun;
      
      CREATE EXTERNAL TABLE default.airflow_metadata_taskinstance (
              sa_instance_state STRING,
              start_date STRING,
              job_id STRING,
              pid STRING,
              end_date STRING,
              pool STRING,
              executor_config STRING,
              duration STRING,
              pool_slots STRING,
              external_executor_id STRING,
              state STRING,
              queue STRING,
              try_number STRING,
              max_tries STRING,
              priority_weight STRING,
              task_id STRING,
              hostname STRING,
              operator STRING,
              dag_id STRING,
              unixname STRING,
              queued_dttm STRING,
              execution_date STRING,
              queued_by_job_id STRING,
              test_mode STRING
         )
      PARTITIONED BY (dt string)
      ROW FORMAT DELIMITED
      FIELDS TERMINATED BY ','
      LOCATION 's3://<DataBucket>/export/taskinstance/'
      TBLPROPERTIES ("skip.header.line.count"="1");
      MSCK REPAIR TABLE default.airflow_metadata_taskinstance;

    6. You can preview the table in the query editor of Amazon Athena.

    7. With the metadata persisted, you can perform pipeline monitoring and derive some powerful insights on the performance of your data pipelines overtime. As an example to illustrate this, execute the below SQL query in Athena.

    This query returns pertinent metrics at a monthly grain which include number of executions of the DAG in that month, success rate, minimum/maximum/average duration for the month and a variation compared to the previous months average.

    Through the below SQL query, you will be able to understand how your data pipelines are performing over time.

    select dag_run_prev_month_calcs.*
            , avg_duration - prev_month_avg_duration as var_duration
    from
        (
    select dag_run_monthly_calcs.*
                , lag(avg_duration, 1, avg_duration) over (partition by dag_id order by year_month) as prev_month_avg_duration
        from
            (
                select dag_id
                        , year_month
                        , sum(counter) as num_executions
                        , sum(success_ind) as num_success
                        , sum(failed_ind) as num_failed
                        , (cast(sum(success_ind) as double)/ sum(counter))*100 as success_rate
                        , min(duration) as min_duration
                        , max(duration) as max_duration
                        , avg(duration) as avg_duration
                from
                    (
                        select dag_id
                                , 1 as counter
                                , case when state = 'success' then 1 else 0 end as success_ind
                                , case when state = 'failed' then 1 else 0 end as failed_ind
                                , date_parse(start_date,'%Y-%m-%d %H:%i:%s.%f+00:00') as start_date
                                , date_parse(end_date,'%Y-%m-%d %H:%i:%s.%f+00:00') as end_date
                                , date_parse(end_date,'%Y-%m-%d %H:%i:%s.%f+00:00') - date_parse(start_date,'%Y-%m-%d %H:%i:%s.%f+00:00') as duration
                                , date_format(date_parse(start_date,'%Y-%m-%d %H:%i:%s.%f+00:00'), '%Y-%m') as year_month
                        from "default"."airflow_metadata_dagrun"
                        where state <> 'running'
                    )  dag_run_counters
                group by dag_id, year_month
            ) dag_run_monthly_calcs
        ) dag_run_prev_month_calcs
    order by dag_id, year_month

    1. You can also visualize this data using your BI tool of choice. While step by step details of creating a dashboard is not covered in this blog, please refer the below dashboard built on Amazon QuickSight as an example of what can be built based on the metadata extracted above. If you are using Amazon QuickSight for the first time, please find the steps here on how to get started.

    Through QuickSight, we can quickly visualise and derive that our data pipelines are completing successfully, but on average are taking a longer time to complete over time.

    Clean up the environment

    1. Navigate to the S3 console and click on the <DataBucket> noted in step 8 above.
    2. Click on Empty bucket.
    3. Confirm the selection.
    4. Repeat this step for bucket <EnvironmentBucket> (noted in step 8 above) and Empty bucket.
    5. Run the below statements in the query editor to drop the two Amazon Athena tables. Run statements individually.
      DROP TABLE default.airflow_metadata_dagrun;
      DROP TABLE default.airflow_metadata_taskinstance;

    6. On the AWS CloudFormation console, select the stack you created and choose Delete.

    Summary

    In this post, we presented a solution to further optimise the costs of Amazon MWAA by tearing down instances whilst preserving the metadata. Storing this metadata in your data lake enables you to better perform pipeline monitoring and analysis. This process can be scheduled and orchestrated programatically and is applicable to all Airflow deployments, such as Amazon MWAA, Apache Airflow installed on Amazon EC2, and even on-premises installations of Apache Airflow.

    To learn more, please visit Amazon MWAA and Getting Started with Amazon MWAA.


    About the Authors

    Praveen Kumar is a Specialist Solution Architect at AWS with expertise in designing, building, and implementing modern data and analytics platforms using cloud-native services. His areas of interests are serverless technology, streaming applications, and modern cloud data warehouses.

    Avnish Jain is a Specialist Solution Architect in Analytics at AWS with experience designing and implementing scalable, modern data platforms on the cloud for large scale enterprises. He is passionate about helping customers build performant and robust data-driven solutions and realise their data & analytics potential.