All posts by Rushabh Lokhande

Inside an enterprise AI agent: A governed, observable loop architecture

Post Syndicated from Rushabh Lokhande original https://aws.amazon.com/blogs/architecture/inside-an-enterprise-ai-agent-a-governed-observable-loop-architecture/

An enterprise AI agent isn’t a bigger chatbot. A chatbot answers one message at a time. An agent keeps working toward a goal: it reads what the user is asking for, breaks the work into steps, pulls in the knowledge it needs, weighs the evidence, calls external tools, and checks the results before it decides whether to keep going or hand back an answer. Every one of those steps touches real systems and real data, so governance, observability, and trust controls must live at each step. Most chatbot designs don’t provide them.

This post lays out a reference architecture for that kind of agent, organized as five layers: an API gateway that handles identity and policy, a five-phase agent runtime (Understand, Plan, Retrieve, Reason, and Act and Observe), a knowledge and state tier that gives the agent memory, a platform-services layer for models and tools, and a trust and control framework that runs across all of them. Each layer maps to AWS managed services. We also cover the design patterns that work and the mistakes we have seen teams make.

The rise of enterprise AI agents

Enterprises are moving past single-turn question-and-answer interfaces for business reasons. They want to automate more of the routine work so their people can spend time elsewhere, ship products and customer experiences faster, and get more done without adding headcount. Those goals justify the investment, but reaching them requires moving from single-turn chatbots to agents that can carry out multi-step work on their own. That jump brings new problems to solve in orchestration, memory, and governance, and the rest of this section is about what those problems demand of the architecture.

From chatbots to agents

Enterprise AI is shifting from systems that answer a question and stop to agents that plan, use tools, and come back with an outcome you can verify. The difference is the loop. Rather than returning one response, an agent cycles through understanding, planning, retrieval, reasoning, and action, and it keeps cycling until it either reaches the user’s goal or decides a human needs to step in.

At AWS re:Invent 2025, Werner Vogels said that the developers who succeed think in systems and build with precision. The teams pulling ahead with agents aren’t the teams that moved first or chose the newest model. They are the ones who treat the whole thing as a system and understand that a choice made in one layer shows up in every layer around it.

What is an AI agent? An AI agent uses a foundation model (FM) as its reasoning core and adds tools, memory, and guardrails so it can take on work that takes more than one step. Where a single-turn chatbot answers and forgets, an agent holds onto state, reasons across several steps, and acts in systems outside itself.

The enterprise imperative: Governed, observable, trustworthy, cost-aware

A capable model is the more straightforward part. Running agents in an enterprise means putting governance, observability, trust controls, policy enforcement, and cost controls around every step they take. Cost matters as much as capability: many enterprises find token spend growing faster than the productivity gains it delivers, so an agent must also be designed to spend inference where it adds value. That is what this architecture is built to do:

  • Governed – Every action clears a policy gate, an approval workflow, or a guardrail before it runs.
  • Observable – Each step emits a trace (latency, tokens, tool status, and execution path) for later audit.
  • Trustworthy – Confidence scoring, evaluations, and human checkpoints sit between the agent and the user.
  • Iterative – The loop sharpens its understanding on each pass as tool results come back.

What this post covers

What follows is a reference architecture for enterprise AI agents on AWS, walked through layer by layer from the first request to the verified result, with diagrams, the AWS services that implement each piece, and the patterns worth copying and avoiding. The aim is to give architects and engineering leaders a shared vocabulary and a mental model for designing these systems.

Architecture overview: The governed agent loop

The AWS Well-Architected Framework Generative AI Lens organizes generative AI workloads around six pillars (operational excellence, security, reliability, performance efficiency, cost optimization, and sustainability), each with its own practices and controls. We split the agent into layers that line up with those pillars, so every layer owns a clear responsibility that traces back to a recognized standard instead of a one-off choice. Teams can change, secure, and scale one layer without disturbing the others while keeping the end-to-end governance the Lens requires.

Layered architecture design

The design is layered and loop-based, with five tiers that each do one job. The agent runtime sits in the middle. It’s a five-phase loop that turns a user’s goal into a verified outcome. Around it sit the layers for knowledge, platform services, trust controls, and the governance that cuts across everything.

Reference architecture diagram

Figure 1 shows the five layers together. Read it top to bottom: the API gateway takes the request and enforces identity and policy, then the flow moves down through the agent runtime, the knowledge and state tier, and the platform services, with the trust and control framework running alongside on the right.
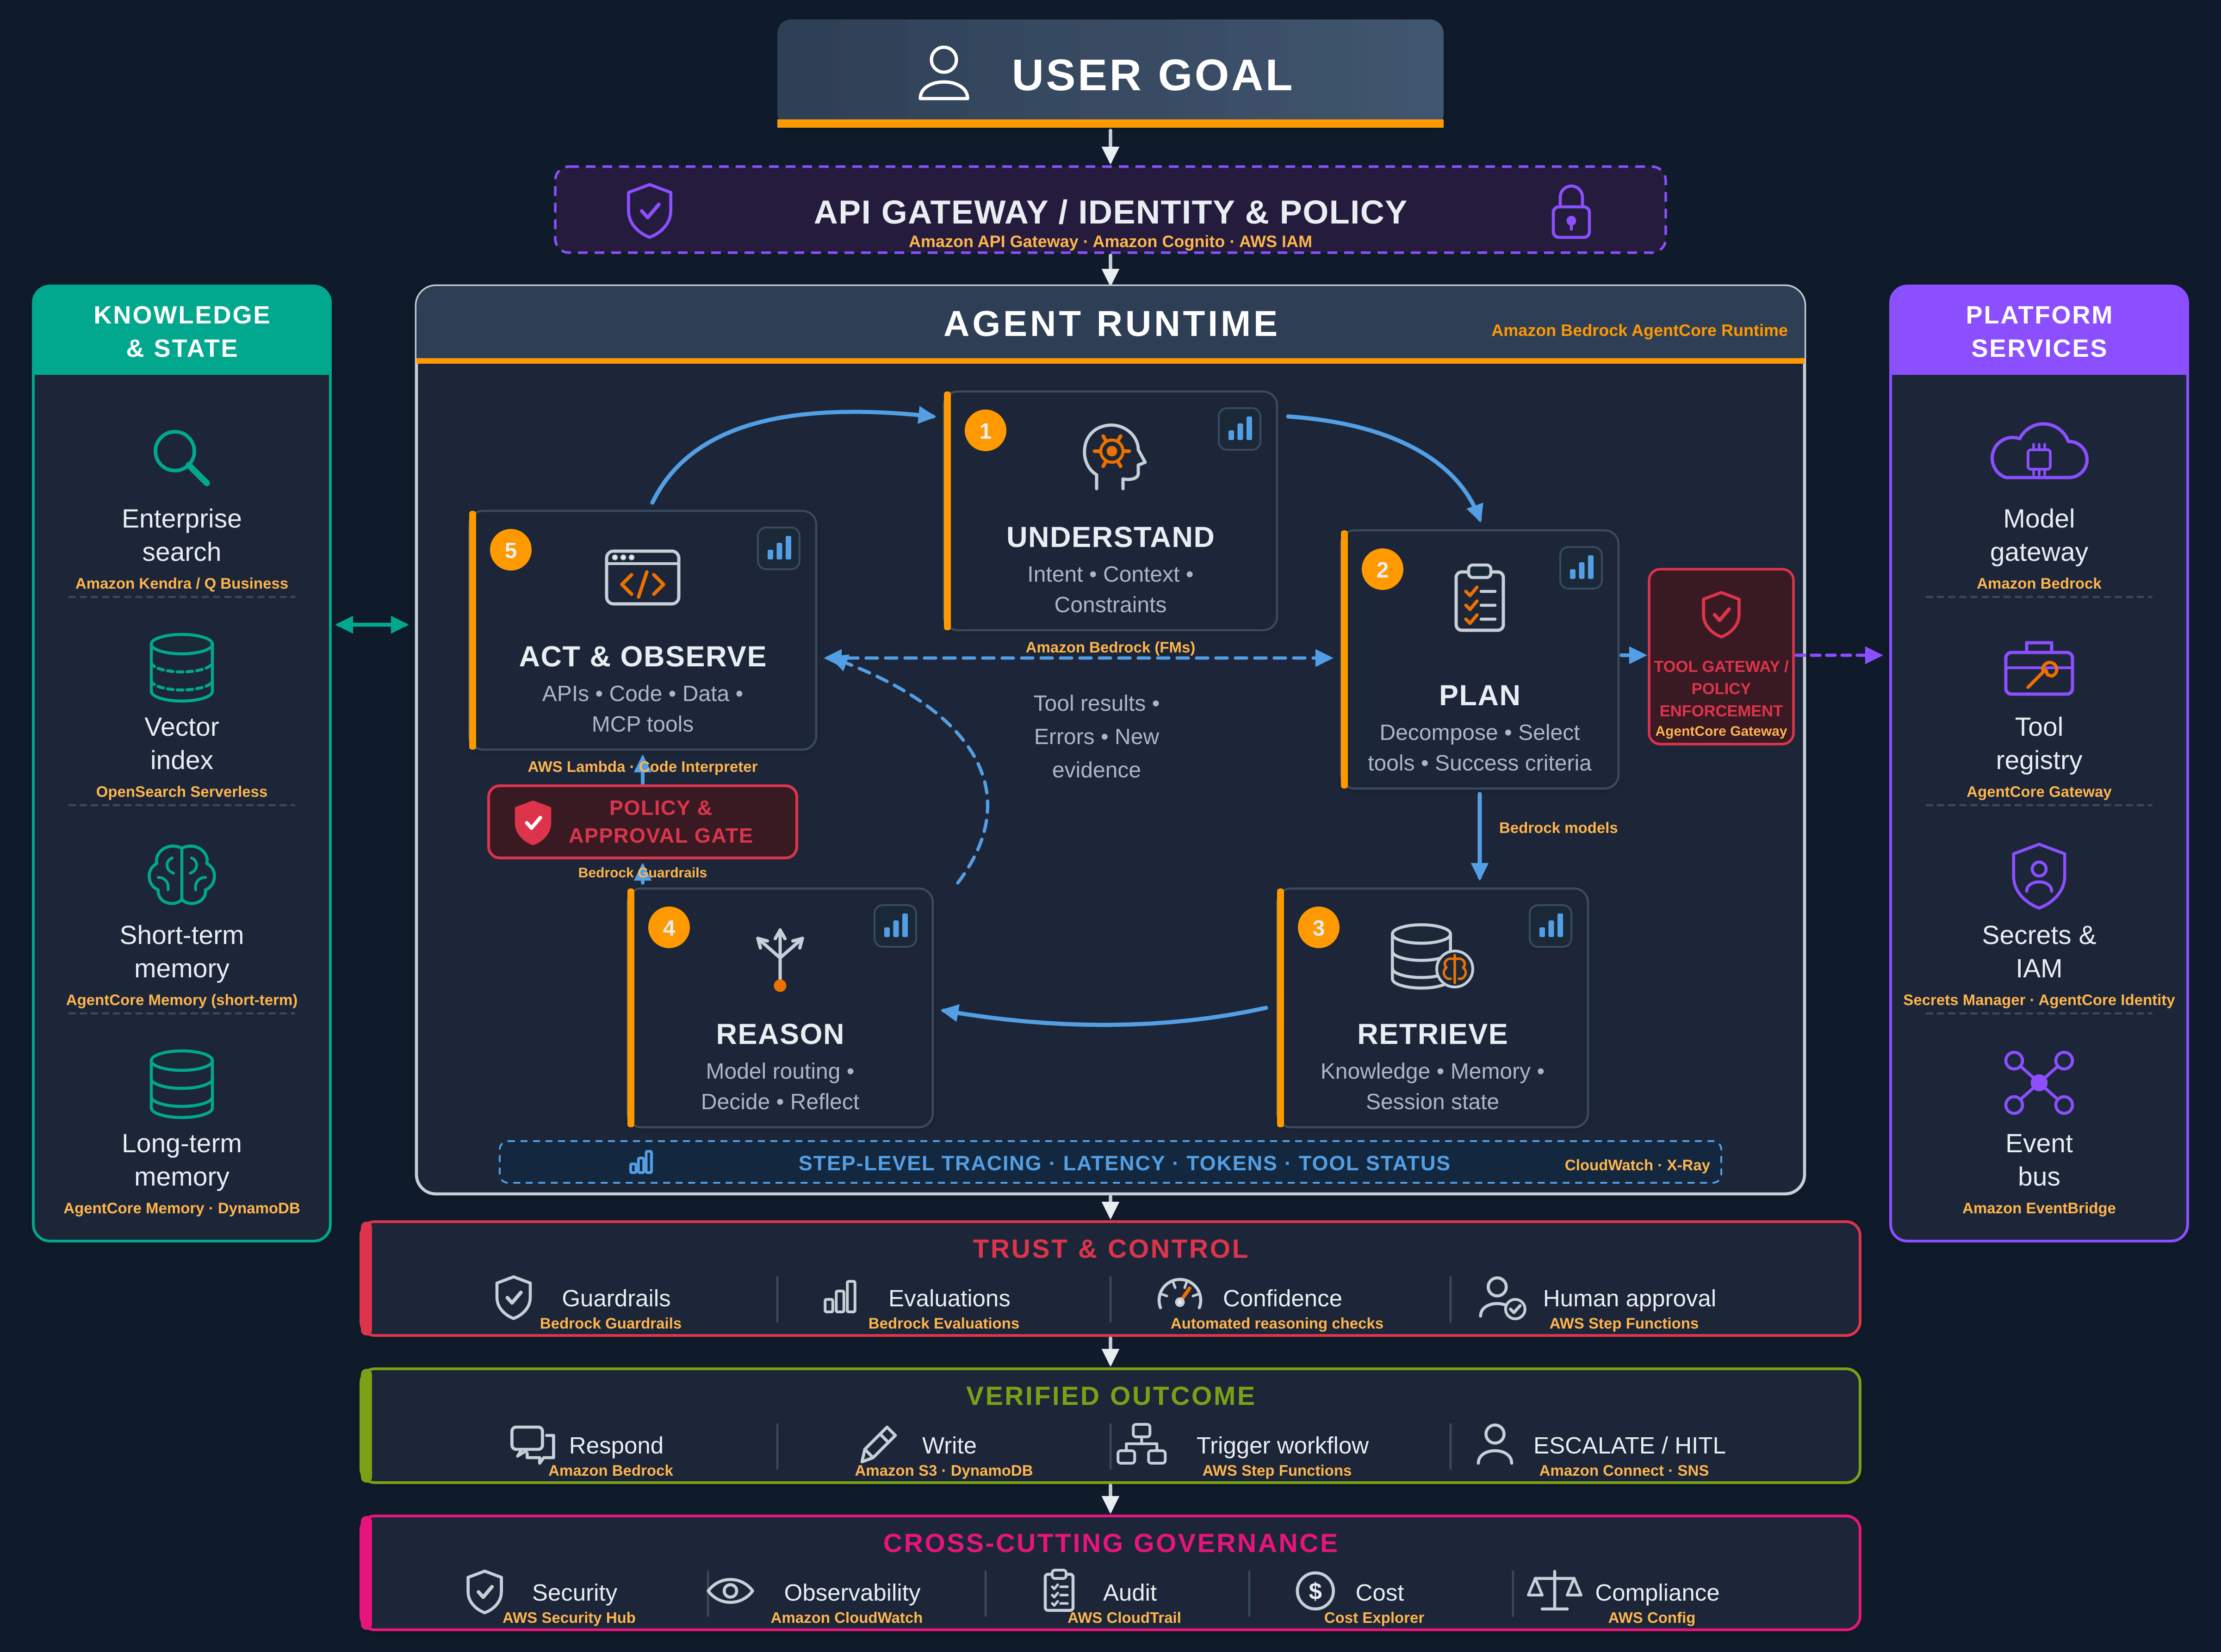
Five-layer enterprise AI agent reference architecture: API gateway, agent runtime, knowledge and state, platform services, and a cross-cutting trust and control framework

Figure 1: Inside an enterprise AI agent, reference architecture

Design principles

Five principles shaped this design, and each one left a mark on the layers you will see later in concrete ways. Zero trust is why identity context travels through every phase of the loop. Observable by default is why there is a dedicated step-level tracing tier instead of leaning on application logs.

These principles aren’t ad-hoc. They come directly from the AWS Well-Architected Framework Generative AI Lens. The Lens’s security guidance maps closely to the following five principles. Least-privilege access across models, data stores, endpoints, and workflows is what zero trust and defense in depth rest on. Securing the data and the traffic between components is separation of concerns in practice. Watching and enforcing the boundaries between the control and data planes is observable by default doing its job. And constraining what the agent is allowed to do, through guardrails and clear limits, is where fail-safe defaults come from. Because it builds on the Lens, this design follows recognized AWS guidance rather than a single team’s convention. It also reflects what AWS Professional Services has implemented and run in production with enterprise customers across industries such as retail and technology: lessons learned in the field that we apply on every engagement, not a set of theoretical best practices. For the full security guidance, see the Generative AI Lens security pillar in the AWS Well-Architected documentation.

Principle Description
Zero trust Every request is authenticated and authorized before reaching the runtime. User identity flows through every phase.
Defense in depth Multiple layers of controls (API gateway, policy gate, trust and control, governance) facilitate no single point of failure.
Separation of concerns Each architectural layer has clear boundaries and responsibilities. Knowledge is separated from compute. Trust is separated from execution.
Observable by default Every step produces telemetry. Tracing, metrics, and logs are first-class architectural concerns, not afterthoughts.
Fail-safe defaults When uncertain, the agent defaults to the safest action: clarify with the user or escalate to a human.

Entry point: User goal and API gateway, identity and policy

Layer 1 of 5 · Entry point: API gateway, identity, and policy (see Figure 1)

Every interaction starts with a user goal: a request in plain language that kicks off the loop. Before it reaches the runtime, it goes through the API gateway and the identity and policy layer, where the zero-trust posture is enforced.

User goal

The user goal starts with a business objective that drives the top-level intent, stated in natural language. It might be as small as “What was our Q3 revenue?” or as involved as “Book a meeting with Sarah, check her calendar availability, and send a summary of our last project discussion.” The agent’s first job is to read that intent and work out the most efficient way to deliver it.

API gateway

The API gateway is the front door for every interaction. It terminates TLS, routes requests (REST, plus WebSocket for streaming responses), applies rate limits, and validates input. On AWS, this is usually Amazon API Gateway with WebSocket APIs for real-time streaming.

Identity and authentication

No request reaches the runtime unauthenticated. The identity layer checks OAuth 2.0 / OpenID Connect (OIDC) tokens, resolves who the caller is, and attaches their context (role, permissions, organization, and session ID) to the request. That context rides along through every later phase, so each tool call and data lookup stays within the caller’s permissions.

Policy enforcement

The policy layer handles role-based access control (RBAC), tool-level permissions, data scoping, and usage quotas. It decides which tools the agent might call for a given user, which data it might touch, and how many tokens it might use in a session.

Component Responsibility AWS service
API gateway TLS termination, request routing, WebSocket streaming, rate limiting Amazon API Gateway, Application Load Balancer (ALB)
Identity Token validation, OAuth 2.0/OIDC, user context injection, session management Amazon Cognito, AWS Identity and Access Management (IAM)
Policy RBAC, tool permissions, data scoping, usage quotas IAM policies, AWS Organizations

Design principle: Zero trust. The gateway authenticates and authorizes every request before it reaches the runtime. The user’s identity, role, and permissions ride on the session context and stay with the request through every phase of the loop.

The agent runtime: Five-phase cognitive loop

Layer 2 of 5 · Agent runtime: the five-phase cognitive loop (see Figure 1)

The runtime performs the core work of the agent. It runs a continuous loop of five phases that track how a careful professional handles a hard task: understand what is being asked, plan an approach, gather the information you need, reason through the choices, then act and watch what comes back before going around again. (see Figure 2)

A note on the model. We aren’t claiming a new theory of agent cognition here. These five phases combine proven ideas under one vocabulary. They draw on the sense, plan, act loop from robotics, the reasoning and acting pattern from ReAct prompting, and the self-reflection step from approaches such as Reflexion (a technique in which the model critiques its own previous attempt and uses that feedback to improve the next one). The enterprise contribution is naming the phases out loud, so you have a clear place to attach governance, observability, and trust controls at each one. If you already think in three or four steps, say plan, act, observe, these phases map directly onto that model.
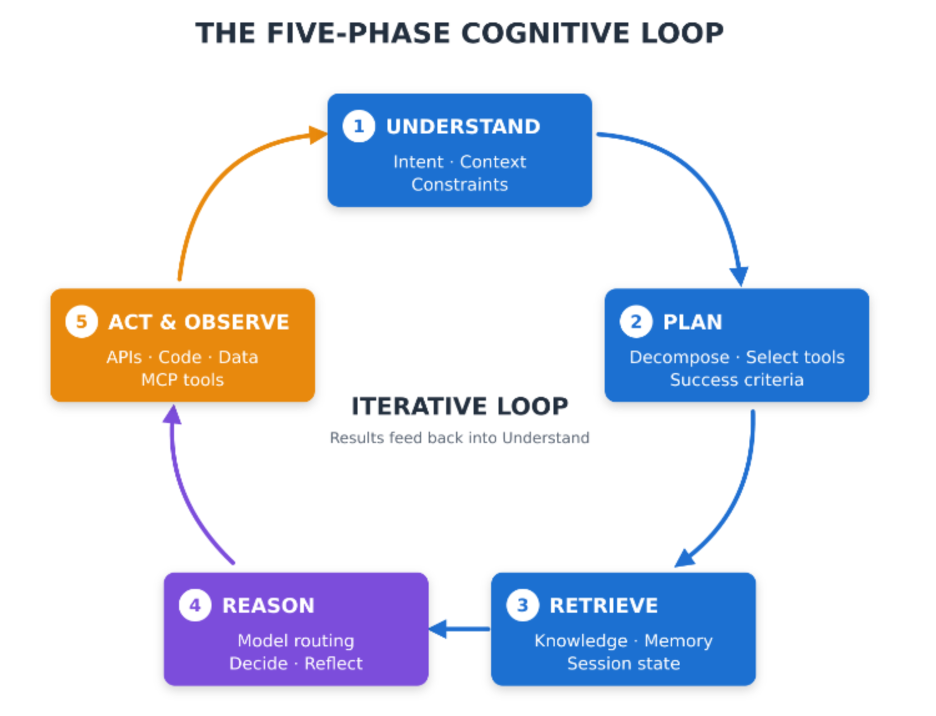
The five-phase agent loop: Understand, Plan, Retrieve, Reason, and Act and Observe, cycling with feedback

Figure 2: The five-phase cognitive loop: Understand, Plan, Retrieve, Reason, Act and Observe

Passes through the loop can end in a final answer, or they can go around again with new evidence from a tool result, an error to handle, or extra context. This ability to refine its work separates an agent from a single large language model (LLM) call.

Phase 1: Understand (intent, context, and constraints)

Understand is the agent’s perception step. It reads the user’s input and pulls out three things:

  • Intent – What the user is actually trying to do. The agent classifies the request type (retrieve information, perform an action, or generate content) and identifies the domain.
  • Context – A working picture built from several sources: the conversation so far (short-term memory), the user’s profile and permissions from the gateway, session state, and relevant history from earlier interactions (long-term memory).
  • Constraints – The boundaries it has to respect: time limits, data access tied to the IAM role, token budgets, which tools are available, and organization-specific policies.

On AWS. Understand usually runs on Amazon Bedrock with a foundation model such as Anthropic Claude or Amazon Nova doing the intent classification. For model availability by AWS Region, refer to Supported models by AWS Region in Amazon Bedrock. The system prompt carries the agent’s persona, its tools, and its behavioral guardrails, and Amazon Bedrock Guardrails filter the input before the model ever sees it.

Phase 2: Plan (decompose, select tools, and define success criteria)

With the intent clear, the agent moves to Plan, where the foundation model breaks the goal into steps.

Sub-step Description Output
Decompose Break the user’s goal into a sequence of sub-tasks. Complex goals might require multiple tool calls and intermediate reasoning steps. Ordered task graph (directed acyclic graph, or DAG)
Select tools For each sub-task, select the appropriate tool(s) from the tool registry using tool descriptions and few-shot examples. Tool-to-task mapping
Success criteria Define what “done” looks like for each sub-task. The Reason phase uses this to evaluate whether a tool call succeeded. Evaluation rubric

No tool runs straight from the plan. Each call first passes through the tool gateway and policy enforcement layer, which checks permissions, inspects the input parameters, applies governance policy, and confirms the request is within budget.

Re-planning. Plan is not a one-shot step. When Reason sees that a sub-task failed or came back wrong, the agent can revise the plan by reordering the task graph, choosing a different tool, or splitting a stubborn step into smaller ones.

Phase 3: Retrieve (knowledge, memory, and session state)

In Retrieve, the agent grounds its reasoning in facts from three sources:

  • Knowledge base (Retrieval Augmented Generation, or RAG) – Semantic search over enterprise documents using embeddings and vector retrieval, with reranking for precision and access filtering for security.
  • Memory – Short-term (the conversation buffer), long-term (preferences and facts it has learned), and episodic (how past tasks turned out).
  • Session state – The current interaction’s tool-result cache, intermediate computations, and external API responses.

The RAG pipeline runs in four stages:

  1. Query rewriting: Optimize the natural language query for search, optionally generating multiple queries for different facets.
  2. Embedding and search: Embed the query and match against the vector index using approximate nearest neighbor (ANN) search.
  3. Reranking: A cross-encoder model reranks initial results for precision, filtering out false positives.
  4. Access filtering: Results are filtered based on the user’s identity and data access policies.

On AWS. Amazon Bedrock Knowledge Bases is the fully managed RAG capability. It handles chunking, embedding with Amazon Titan Embeddings, and vector storage in Amazon OpenSearch Serverless. For memory, Amazon DynamoDB holds session state and Amazon ElastiCache caches recent results for low-latency reads.

Phase 4: Reason (model routing, decide, and reflect)

Reason is where the model turns evidence into a decision. With the retrieved context in hand, it does three things:

  • Model routing – Pick the right model for this step. Simple work goes to smaller, faster models. Complex reasoning goes to a larger, more capable model. That keeps cost and latency down, and it’s one of the most effective cost-optimization levers in the architecture.
  • Decision – Combine what was retrieved with the plan to decide the next tool call, the parameters to pass, whether the plan needs changing, or whether to ask a clarifying question.
  • Reflection – Look at the result of each action. Did the call succeed? Does the output match what was expected? Does the plan need to change?

Anti-pattern: Infinite loops. Knowing when to stop is a core design problem. With no safeguards, an agent can get stuck reasoning in circles. The usual defenses are a cap on iterations, a timeout budget, classifying errors as transient or permanent, and a path to escalate to a human. Getting this wrong costs more than one unfinished task. A looping agent keeps calling the model and its tools, so token spend and compute climb with every wasted pass and nothing gets done. The effects compound. Latency rises and service level agreements (SLAs) slip. Downstream APIs and model endpoints absorb redundant load, which can trigger throttling for other workloads. The user waits on a request that never completes, which erodes the trust this architecture exists to protect. Caps on iterations, time, and tokens, plus an escalation path, keep a confused agent from turning into a runaway bill.

Phase 5: Act and observe (APIs, code, data, and MCP tools)

Act and Observe is where the agent reaches into the outside world. It carries the most governance risk because it changes real systems.

  • Tool execution – The agent calls external tools through standard interfaces (REST APIs, code sandboxes, data connectors, and Model Context Protocol (MCP) tools) and logs every call with its full request and response.
  • Observation – Each result is parsed, validated, and fed back into context: structured returns, error messages, status codes, side effects.
  • Approval gate – Before a destructive action runs (a write, delete, or send), it goes through the policy and approval gate. Depending on the risk and the organization’s policy, that is an automated check, a human sign-off, or both.

The feedback loop

When a tool returns success, an error, or partial data, the result flows back into Understand and becomes part of the context for the next pass. Each pass through the loop uses this new context to move closer to the right answer. What flows back includes:

  • Tool results: Structured data, API responses, and computation outputs.
  • Errors: Error messages, timeouts, and permission denials that inform replanning.
  • New evidence: Information discovered during tool execution that changes the understanding of the task.

Tool gateway and policy enforcement

The tool gateway sits between the runtime and the platform services, and it’s the single checkpoint every tool call goes through. It runs the RBAC checks, validates input, applies governance policy, and enforces rate limits and cost budgets. On AWS, that maps to Amazon Bedrock Agent action groups with IAM-based authorization, and you can add AWS Lambda authorizers when you need custom policy logic.

Knowledge and state layer

Layer 3 of 5 · Knowledge and state (see Figure 1)

The knowledge and state layer gives the agent two things it cannot work without: factual grounding and memory that survives across sessions. It’s organized as four tiers:

Tier Purpose AWS service
Enterprise search Full-text and semantic search across organizational knowledge bases, documentation, and wikis. Amazon Kendra, Amazon OpenSearch Service
Vector index Embeddings store for RAG retrieval. Supports approximate nearest neighbor search for semantic similarity. Amazon OpenSearch Serverless, Amazon Aurora PostgreSQL (pgvector), Amazon S3 Vectors
Short-term memory Conversation buffer and session context window. Provides continuity within a single interaction. Amazon ElastiCache, Amazon DynamoDB (time to live, or TTL)
Long-term memory User preferences, learned patterns, facts, and knowledge graph. Persists across sessions. Amazon DynamoDB, Amazon Neptune

Platform services layer

Layer 4 of 5 · Platform services (see Figure 1)

The platform services layer is the shared infrastructure the runtime depends on. These managed services keep operational complexity out of the agent.

Model gateway

The model gateway is one interface in front of many foundation models. It routes each task to the right model, falls back to another when one fails, and handles rate limiting, token metering, and response caching. Because it hides each provider’s API behind a common schema, you can swap models without touching agent code.

On AWS, Amazon Bedrock is that gateway, with serverless access to a growing lineup of foundation models including Anthropic Claude, Amazon Nova, Meta Llama, and Mistral. For model availability by Region, refer to Supported models by AWS Region in Amazon Bedrock. To run custom models, use Amazon SageMaker endpoints for managed inference with automatic scaling.

Tool registry

The tool registry is the catalog of every API, function, and connector the agent can call, along with their schemas, permissions, descriptions, and versions. Plan reads this registry to choose tools for each sub-task. Each tool is registered with an OpenAPI schema that spells out its inputs, outputs, and side effects.

On AWS, Amazon Bedrock Agent action groups hold those schemas and wire them to AWS Lambda functions or API endpoints, giving you a governed, versioned catalog the agent can discover and call.

Secrets and IAM

This is where API keys, database credentials, and OAuth tokens live and get rotated. Fine-grained IAM policies decide which agents can reach which secrets, so credentials don’t leak into a trace or a log. AWS Secrets Manager handles the rotation, and IAM enforces least privilege.

Event bus

The event bus moves agent lifecycle events (start, tool call, completion, and error) asynchronously, which lets monitoring, alerting, and downstream integrations stay decoupled from the agent. Amazon EventBridge is the backbone, with Amazon Simple Notification Service (Amazon SNS) and Amazon Simple Queue Service (Amazon SQS) for fan-out and queuing.

Observability: Step-level tracing

Watching an agent isn’t like watching a normal application. An agent runs a non-deterministic loop. The number of steps varies, tool calls branch, and plans change mid-execution. Step-level tracing must capture the full execution graph, not only the request and response.

At every step, the observability layer captures four kinds of signal:

Signal What it captures Why it matters
Step-level tracing Parent-child span relationships, phase transitions, decision branching points Debug non-deterministic behavior. Trace root cause of incorrect outputs
Latency Per-step wall clock time, model inference time, tool round-trip time Identify bottlenecks. SLA compliance. Performance optimization
Tokens Input and output tokens per model call, context window utilization, cumulative usage Cost attribution and optimization (per user, tenant, and workflow). Context overflow prevention. Prompt optimization
Tool status Tool call success/failure rates, response codes, retry counts, payload sizes Tool reliability scoring. Automatic fallback decisions. SLA monitoring

On AWS – Use AWS X-Ray with custom segments for the agent’s steps, Amazon CloudWatch for metrics and alarms, and Amazon CloudWatch Logs Insights to query trace data. Amazon Bedrock logs model invocations natively, with the input and output payloads and token counts.

Trust and control framework

Layer 5 of 5 · Trust and control, with cross-cutting governance (see Figure 1)

A lack of trust is the main barrier to deploying enterprise agents. This layer sits between the runtime and the final output and runs each action through a series of gates to confirm it meets the organization’s standards before it ships. These controls also help organizations meet the obligations of emerging regulatory frameworks such as the EU AI Act, helping reduce exposure to penalties and keep AI use compliance-aware and responsible. (see Figure 3)

Grounded in recognized standards. The four gates aren’t an arbitrary sequence. Each one maps to a responsible-AI control that already exists. They track the responsible-AI dimensions of the AWS Well-Architected Generative AI Lens (safety, veracity and robustness, controllability, transparency, and governance) and the risk functions in the NIST AI Risk Management Framework (govern, map, measure, manage). The mapping is direct. Gate 1, guardrails, is the safety gate: it filters harmful content and the output-handling risks in the OWASP Top 10 for LLM Applications. Gate 2, evaluations, is where veracity and robustness get checked, through groundedness and hallucination tests. Gate 3, confidence scoring, is the transparency gate. It surfaces uncertainty and shows the source of each claim. Gate 4, human approval, is what keeps a person in control as the system scales. Measured against standards like these, the pipeline is auditable on terms reviewers and regulators already know, rather than an internal checklist.
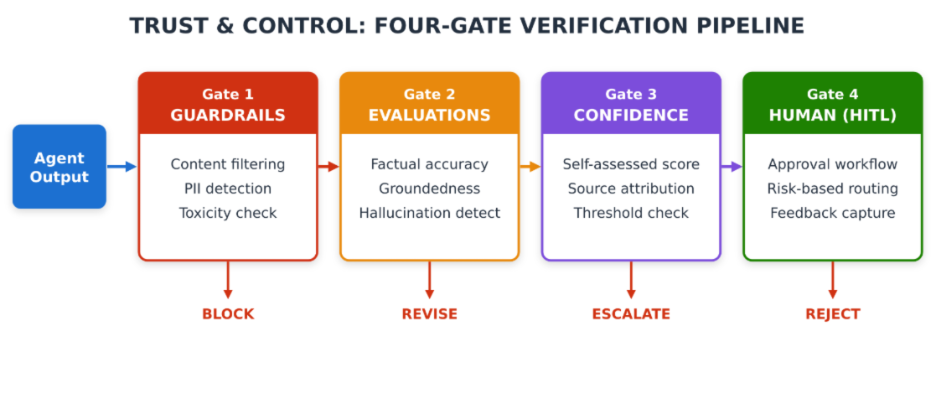
Four-gate trust and control pipeline: guardrails, evaluations, confidence scoring, and human approval

Figure 3: Trust and control, four-gate verification pipeline

Gate 1: Guardrails

Content filtering, personally identifiable information (PII) detection, toxicity checks, and topic deny-lists. Guardrails work on the output, scanning the agent’s response before the user sees it. On AWS, Amazon Bedrock Guardrails gives you configurable filters for hate, insults, sexual content, violence, and misconduct, plus your own denied topics and PII redaction.

Gate 2: Evaluations

This gate checks whether the retrieved content supports the response. This gate covers groundedness, hallucination detection, and format validation, and it can hand the output to a separate “judge” model to score the primary model’s work.

Gate 3: Confidence scoring

The agent rates its own confidence, attributes its key claims to sources, flags where it is unsure, and checks that confidence against a threshold. Anything below the line goes to a human instead of straight to the user.

Gate 4: Human approval (HITL)

For high-risk actions, such as moving money, modifying data, or sending external communications, the agent routes through a human-in-the-loop (HITL) approval step. The reviewer sees the proposed action, the agent’s reasoning, and the confidence score, and can approve it, change it, or reject it. Every decision is logged.

Verified outcomes

After an action clears the gates, it ends up as one of four outcome types, each with its own governance bar:

Outcome Description Risk level Governance
Respond Generate a natural language response to the user. Lowest risk: guardrails and content filters are sufficient. Low Guardrails only
Write Create or modify data in an external system (database record, document, configuration). Medium Policy gate + logging
Trigger workflow Initiate an automated workflow or pipeline (deployment, data pipeline, notification chain). High Policy + HITL approval
Escalate / HITL Agent determines that human intervention is needed: confidence too low, action too risky, or request out of scope. Critical Full approval chain

Cross-cutting governance

Governance is the layer underneath everything else. It helps the organization operate within its legal, regulatory, and ethical requirements at every level, and it rests on five pillars (see Figure 4):
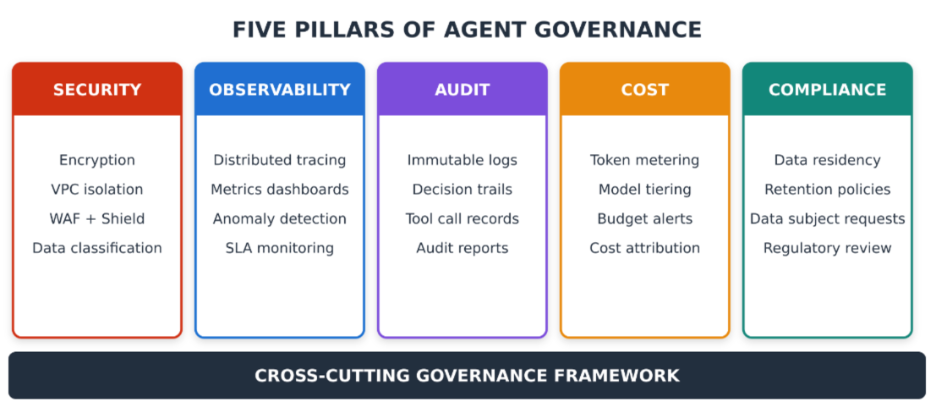
Five pillars of agent governance: security, observability, audit, cost, and compliance

Figure 4: Five pillars of agent governance

  • Security: Encryption at rest and in transit, virtual private cloud (VPC) isolation, AWS WAF and AWS Shield protection, data classification, and network segmentation.
  • Observability: Distributed tracing, metrics dashboards, anomaly detection, alert routing, and SLA monitoring across all agent operations.
  • Audit: Immutable audit logs, decision trails, tool call records, data lineage tracking, and automated compliance reports.
  • Cost: Token metering per user and team, model tiering for cost optimization, budget alerts, per-user quotas, and cost attribution dashboards.
  • Compliance: Considerations such as data residency, retention policies, and mechanisms to support data subject requests (for example, access and deletion) that your organization might need to address under regulations like GDPR or CCPA. If your workload processes protected health information, use HIPAA eligible services and review your responsibilities under the AWS Shared Responsibility Model. AWS compliance programs such as SOC 2 cover the underlying AWS services, not your application. See AWS Services in Scope by Compliance Program.

Design patterns and best practices

The following patterns and anti-patterns come from AWS Professional Services engagements in which we built and ran enterprise agents in production with customers, not from a whiteboard.

Teams already run architectures like this in production on AWS. One of these is Druva, a data security provider, which built DruAI, a multi-agent system on Amazon Bedrock AgentCore where specialized agents handle telemetry analysis, investigation guidance, and recovery workflows. According to the Druva case study, 68 percent of customer issues are now resolved through agent workflows, support-assisted resolution is 58 percent faster, and cyber investigations that once took 30–60 days now finish in minutes. Separately, Cox Automotive used Amazon Bedrock AgentCore to move 17 agentic solutions into production in under a year, with seven more in development. This architecture reflects patterns from these deployments.

These patterns answer design questions that keep coming up when teams build enterprise agents. Each pattern stands on its own. Adopt the ones that fit your workload and leave the rest.

Pattern: Graduated autonomy

Start agents read-only and widen their write access a step at a time as they earn trust. Use feature flags or IAM role escalation to set the autonomy level per user, team, or use case. That way the organization builds confidence in the system before handing it broader permissions.

Pattern: Fail-safe defaults

When the agent encounters a missing tool, an API timeout, or an ambiguous request, it should take the safe route: ask a clarifying question instead of guessing, or escalate to a human instead of risking a bad action. Encode this in the system prompt and back it up in the trust and control layer.

Pattern: Multi-model strategy

Match the model to the phase. Small, fast models can handle intent classification and simple routing (Phase 1). Larger models justify their cost in planning and reasoning (Phases 2 and 4). Specialized models do the evaluations in the trust layer. Teams that route this way usually cut cost while keeping quality where it counts, though the actual savings depend on your mix of work, your model choices, and your traffic. Benchmark against your own use cases before you commit to a target.

Pattern: Structured tool interfaces

Give every tool an explicit OpenAPI schema that defines input and output types, error codes, rate limits, and declared side effects. That is what lets Plan pick tools intelligently and lets Observe check what came back against what was promised.

Anti-patterns to avoid

These are the traps we have watched teams fall into early. Recognizing them early reduces rework.

Anti-pattern: Monolithic agent

Resist the urge to build one agent that does everything. Split the work into specialized agents (for example, calendar, code, and data analysis) coordinated by a supervisor agent. You get better reliability, straightforward testing, and the freedom to scale and deploy each one on its own.

Anti-pattern: Unbounded loops

Put a hard ceiling on loop iterations. A common production setting is 3 to 5 iterations against a total token budget. Past that, the agent should summarize where it got to and either escalate or ask the user what to do. Without that ceiling, a confused agent can spend tokens indefinitely and still get nowhere.

Anti-pattern: Trust-later architecture

Don’t file implementing governance, guardrails, and observability under “later.” They must be primitives from day one. Bolting trust controls onto an agent that is already in production costs more and introduces more defects than building them in from the start.

Bringing this architecture to life on AWS

This section takes the Figure 1 reference architecture and grounds it in concrete AWS services, mapping each layer of the five-layer loop to the managed services that implement it. Treat it as a set of sensible starting points, not a fixed bill of materials. Your scale, data residency, latency, and cost requirements will push some of these choices around, so use the mappings as a baseline, check them against the AWS Well-Architected Generative AI Lens, and tune for your own workload.

Mapping architecture layers to AWS services

Walking Figure 1 from the entry point down to verified outcomes, here is how each layer lands on AWS.

Layer 1: Entry point.

Configure Amazon API Gateway with a WebSocket API for streaming agent responses. Attach an Amazon Cognito user pool for OAuth 2.0/OIDC authentication. Define IAM policies that scope tool access by user role.

Layer 2: Agent runtime.

Create an Amazon Bedrock Agent with a system prompt that encodes your agent’s persona, behavioral guardrails, and the list of available tools. Define action groups that map to AWS Lambda functions or API endpoints. Enable Amazon Bedrock Guardrails for input and output filtering.

Layer 3: Knowledge and state.

Create an Amazon Bedrock Knowledge Base backed by Amazon Simple Storage Service (Amazon S3) as the data source and Amazon OpenSearch Serverless as the vector store. Configure Amazon DynamoDB tables for session state (with TTL for automatic expiry) and long-term memory. Optionally, add Amazon ElastiCache for low-latency result caching.

Layer 4: Platform services.

Amazon Bedrock acts as the model gateway. Register tools as Amazon Bedrock Agent action groups with OpenAPI schemas. Store API keys and credentials in AWS Secrets Manager with automatic rotation enabled. Configure Amazon EventBridge rules for agent lifecycle events.

Layer 5: Observability and governance.

Turn on Amazon Bedrock model invocation logging. Configure AWS X-Ray tracing for AWS Lambda functions. Set up Amazon CloudWatch dashboards for token usage, latency percentiles, and tool success rates. Turn on AWS CloudTrail for audit logging and AWS Config rules for compliance checks.

From baseline to production. These mappings give you a governed starting point, but most of the engineering effort goes into hardening this baseline into a production-grade agent tuned to your security, compliance, cost, and scale requirements. If you want to accelerate that journey, AWS Professional Services and AWS Partners can help you design, build, and operate this architecture for your own workloads. Learn more about engaging AWS Professional Services or finding an AWS Partner. Work with your security and legal teams to meet your organizational security, regulatory, and compliance requirements before deployment. Under the AWS Shared Responsibility Model, you are responsible for configuring and operating these services to meet those requirements.

Conclusion

The hard part of an enterprise agent was never the model. It’s everything around the model. That includes the identity that follows a request, the memory that persists, the gates an action clears, and the traces that show what happened. Get those right and the agent becomes something a business can actually rely on. Skip them and you have a clever demo that no one will put in front of a customer.

The governed, observable loop in this post is a reference point for teams moving past basic chatbots toward agents they can trust in production.

A few things worth holding onto:

  1. Governance isn’t a feature. It belongs in every layer, not bolted on at the end.
  2. You can’t govern what you cannot see. Step-level tracing is what makes reliable agent operations possible.
  3. The loop is the point. The five-phase loop, with feedback on every pass, is what distinguishes an agent from a chatbot.
  4. Trust is earned in steps. Start narrow and read-only, then widen as the system proves itself.
  5. The pieces are already on AWS. Amazon Bedrock for models and guardrails, Amazon EventBridge for event-driven observability, and AWS IAM for access control. Every component maps to a managed service.

Next steps

Further reading

For a service-by-service reference that maps these architectural layers to AWS offerings, refer to the AWS Prescriptive Guidance on agentic AI: Foundations of Agentic AI on AWS covers the conceptual foundations, and Enterprise Multi-Account Architecture for Agentic AI covers production infrastructure. Because managed services evolve, these guides are kept current with the recommended services for each layer.

About the authors

Rushabh Lokhande

Rushabh Lokhande

Rushabh Lokhande is a Senior Data and AI Engineer at AWS Professional Services, where he helps enterprise customers design, build, and scale generative and agentic AI solutions on AWS. He specializes in taking LLM workloads from prototype to production, with a focus on governance, observability, and cost optimization.

Paul Tamburello

Paul Tamburello

Paul is the Data & AI Leader at AWS Professional Services in North America. He supports customers to modernize and transform their business utilizing AI on AWS. He focuses on enterprise Data and AI strategy for all industries, leveraging the latest in AI technologies.

Automate marketing campaigns with real-time customer data using Amazon Pinpoint

Post Syndicated from Rushabh Lokhande original https://aws.amazon.com/blogs/messaging-and-targeting/automate-marketing-campaigns-with-real-time-customer-data-using-amazon-pinpoint/

Amazon Pinpoint offers marketers and developers one customizable tool to deliver customer communications across channels, segments, and campaigns at scale. Amazon Pinpoint makes it easy to run targeted campaigns and drive customer communications across different channels: email, SMS, push notifications, in-app messaging, or custom channels. Amazon Pinpoint campaigns enables you define which users to target, determine which messages to send, schedule the best time to deliver the messages, and then track the results of your campaign.

In many cases, the customer data resides in a third-party system such as a CRM, Customer Data Platform, Point of Sales, database and data warehouse. This customer data represents a valuable asset for your organization. Your marketing team needs to leverage each piece of this data to elevate the customer experience.

In this blog post we will demonstrate how you can leverage users’ clickstream data stored in database to build user segments and launch campaigns using Amazon Pinpoint. Also, we will showcase the full architecture of the data pipeline including other AWS services such as Amazon RDS, AWS Data Migration Service, Amazon Kinesis and AWS Lambda.

Let us understand our case study with an example: a customer currently has digital touch points such as a Website and a Mobile App to collect the users’ clickstreams and behavioral data where they are storing them in a MySQL database. Marketing teams want to leverage the collected data to deliver a personalized experience by leveraging Amazon Pinpoint capabilities.

You can find below the detail of a specific use case covered by the proposed solution:

  • All the clickstream and customer data are stored in MySQL DB
  • Your marketing team wants to create a personalized Amazon Pinpoint campaigns based on the user status and experience. Ex:
    • Customers who interested in specific offering to activate for them campaign based on their interest
    • Communicate with the preferred language of the user

Please note that this use case is used to showcase the proposed solution capabilities. However, it is not limited to this specific use case since you can leverage any customer collected dimension/attribute to create specific campaign to achieve a specific marketing use case.

In this post, we provide a guided journey on how marketers can collect, segment, and activate audience segments in real-time to increase their agility in managing campaigns.

Overview of solution

The use case covered in this post, focuses on demonstrating the flexibility offered by Amazon Pinpoint in both inbound (Ingestion) and outbound (Activation) stream of customer data. For the inbound stream, Amazon Pinpoint gives you a variety of ways to import your customer data, including:

  1. CSV/JSON import from the AWS console
  2. API operation to create a single or multiple endpoints
  3. Programmatically create and execute import jobs

We will focus on building a real-time inbound stream of customer data available within an Amazon RDS MySQL database specifically. It is important to mention that similar approach can be implemented to ingest data from third-party systems if any.

For the outbound stream, activating customer data using Amazon Pinpoint can be achieved using the following two methods:

  1. Campaign: a campaign is a messaging initiative that engages a specific audience segment.
  2. Journey: a journey is a customized, multi-step engagement experience.

The result of customer data activation cannot be completed without specifying the targeted channel. A channel represents the platform through which you engage your audience segment with messages. For example, Amazon Pinpoint customers can optimize how they target notifications to prospective customers through LINE message and email. They can deliver notifications with more information on prospected customer’s product information such as sales, new products etc. to the appropriate audience.

Amazon Pinpoint supports the following channels:

  • Push notifications
  • Email
  • SMS
  • Voice
  • In-app messages

In addition to these channels, you can also extend the capabilities to meet your specific use case by creating custom channels. You can use custom channels to send messages to your customers through any service that has an API including third-party services. For example, you can use custom channels to send messages through third-party services such as WhatsApp or Facebook Messenger. We will focus on developing an Amazon Pinpoint connector using custom channel to target your customers on third-party services through API.

Solution Architecture

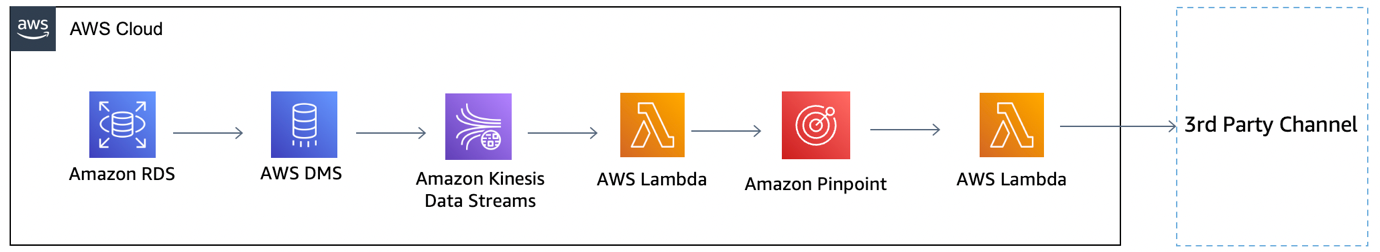
The below diagram illustrates the proposed architecture to address the use case. Moving from left to right:

Fig 1: Architecture Diagram for the Solution

Fig 1: Architecture Diagram for the Solution

  1. Amazon RDS: This hosts customer database where you can have one or many tables contains customer data.
  2. AWS Data Migration Service (DMS): This acts as the glue between Amazon RDS MySQL and the downstream services by replicating any transformation that happens at the record level in the configured customer tables.
  3. Amazon Kinesis Data Streams: This is the destination endpoint for AWS DMS. It will carry all the transformed records for the next stage of the pipeline.
  4. AWS Lambda (inbound): The inbound AWS Lambda triggers the Kinesis Data Streams, process the mutated records, and ingest them in Amazon Pinpoint.
  5. Amazon Pinpoint: This act as the centralized place to define customer segments and launch campaigns.
  6. AWS Lambda (outbound): This act as the custom channel destination for the campaigns activated from Amazon Pinpoint.

To illustrate how to set up this architecture, we’ll walk you through the following steps:

  1. Deploying an AWS CDK stack to provision the following AWS Resources
  2. Validate the Deployment.
  3. Run a Sample Workflow – This workflow will run an AWS Glue PySpark job that uses a custom Python library, and an upgraded version of boto3.
  4. Cleaning up your resources.

Prerequisites

Make sure that you complete the following steps as prerequisites:

The Solution

Launching your AWS CDK Stack

Step 1a: Open your device’s command line or Terminal.

Step1b: Checkout Git repository to a local directory on your device:

git clone https://github.com/aws-samples/amazon-pinpoint-realtime-campaign-optimization-example.git

Step 2: Change directories to the new directory code location:

cd amazon-pinpoint-realtime-campaign-optimization-example

Step 3: Update your AWS account number and region:

  1. Edit config.py with your choice to tool or command line
  2. look for section “Account Setup” and update your account number and region

    Fig 2: Configuring config.py for account-id and region

    Fig 2: Configuring config.py for account-id and region

  3. look for section “VPC Parameters” and update your VPC and subnet info

    Fig 3: Configuring config.py for VPC and subnet information

    Fig 3: Configuring config.py for VPC and subnet information

Step 4: Verify if you are in the directory where app.py file is located:

ls -ltr app.py

Step 5: Create a virtual environment:

macOS/Linux:

python3 -m venv .env

Windows:

python -m venv .env

Step 6: Activate the virtual environment after the init process completes and the virtual environment is created:

macOS/Linux:

source .env/bin/activate

Windows:

.env\Scripts\activate.bat

Step 7: Install the required dependencies:

pip3 install -r requirements.txt

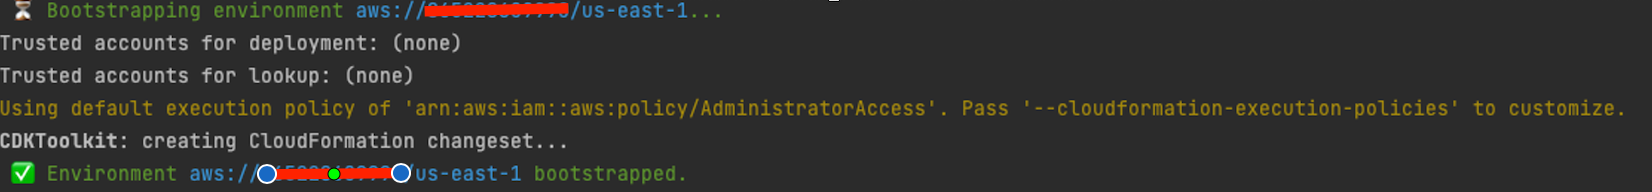
Step 8: Bootstrap the cdk app using the following command:

cdk bootstrap aws://<AWS_ACCOUNTID>/<AWS_REGION>

Replace the place holder AWS_ACCOUNTID and AWS_REGION with your AWS account ID and the region to be deployed.
This step provisions the initial resources, including an Amazon S3 bucket for storing files and IAM roles that grant permissions needed to perform deployments.

Fig 4: Bootstrapping CDK environment

Fig 4: Bootstrapping CDK environment

Please note, if you have already bootstrapped the same account previously, you cannot bootstrap account, in such case skip this step or use a new AWS account.

Step 9: Make sure that your AWS profile is setup along with the region that you want to deploy as mentioned in the prerequisite. Synthesize the templates. AWS CDK apps use code to define the infrastructure, and when run they produce or “synthesize” a CloudFormation template for each stack defined in the application:

cdk synthesize

Step 10: Deploy the solution. By default, some actions that could potentially make security changes require approval. In this deployment, you’re creating an IAM role. The following command overrides the approval prompts, but if you would like to manually accept the prompts, then omit the –require-approval never flag:

cdk deploy "*" --require-approval never

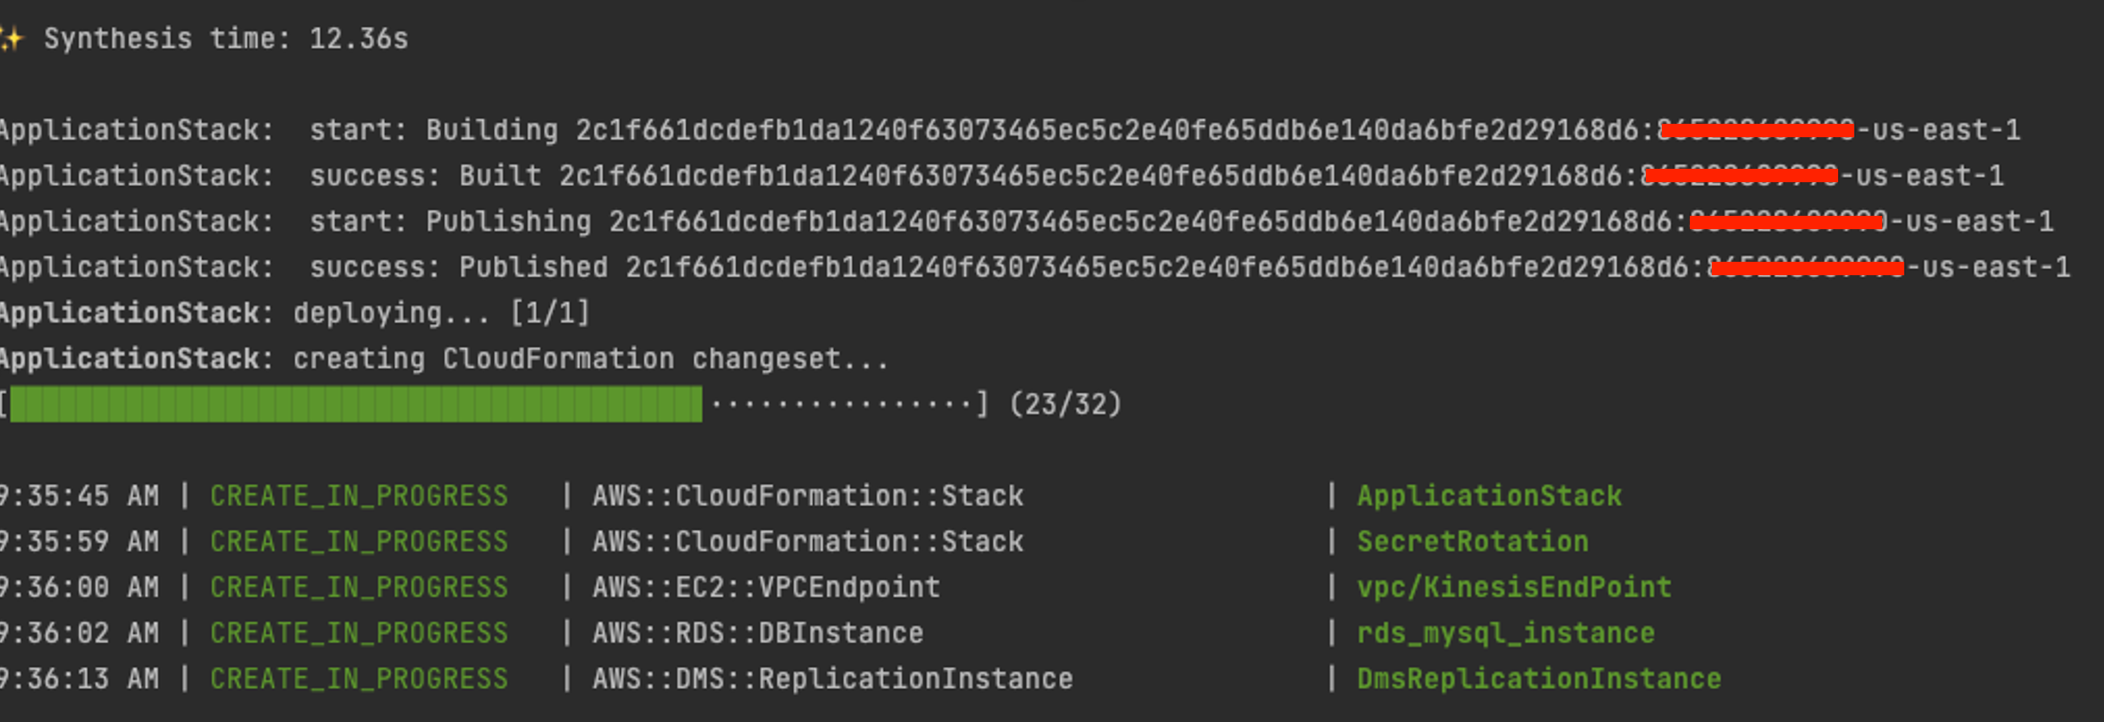
While the AWS CDK deploys the CloudFormation stacks, you can follow the deployment progress in your terminal.

Fig 5: AWS CDK Deployment progress in terminal

Fig 5: AWS CDK Deployment progress in terminal

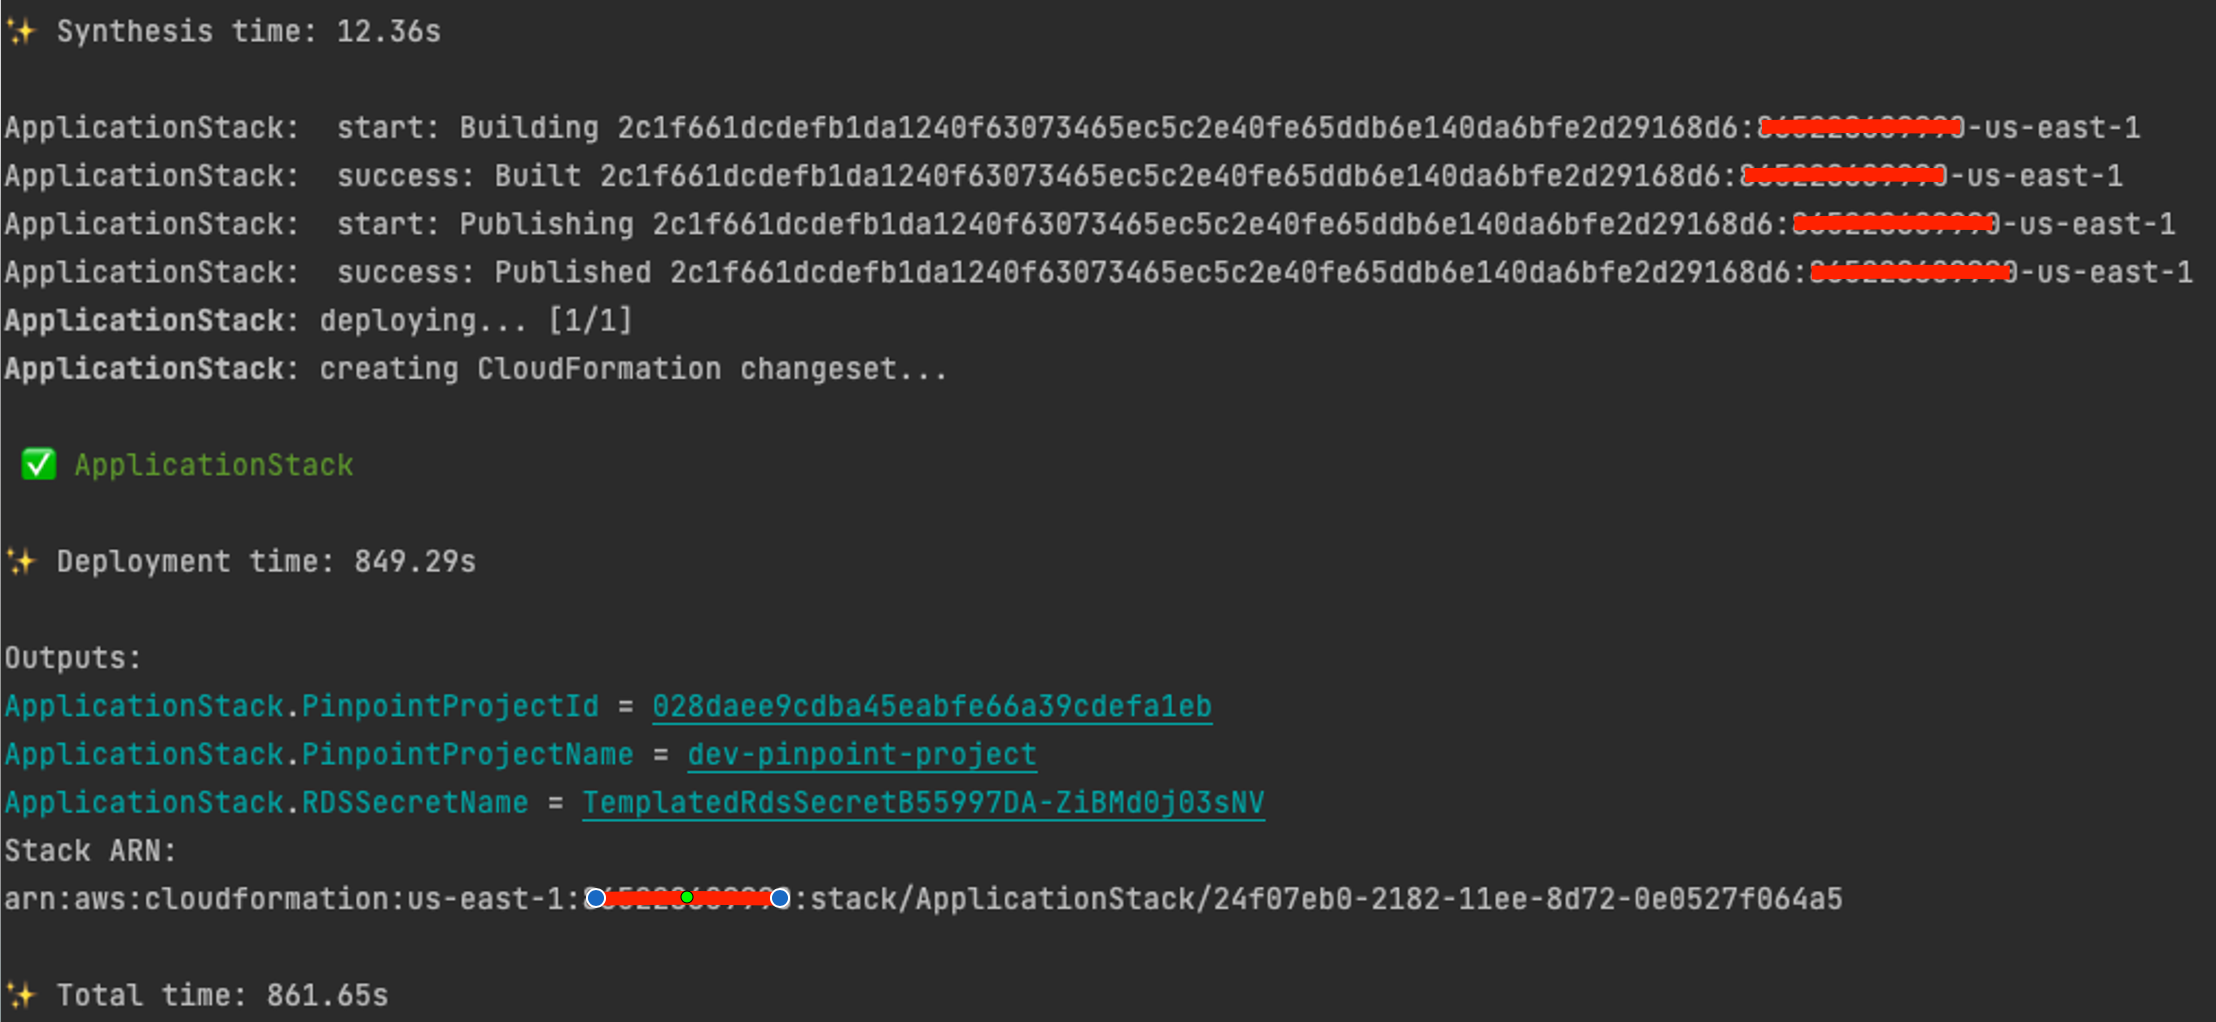
Once the deployment is successful, you’ll see the successful status as follows:

Fig 6: AWS CDK Deployment completion success

Fig 6: AWS CDK Deployment completion success

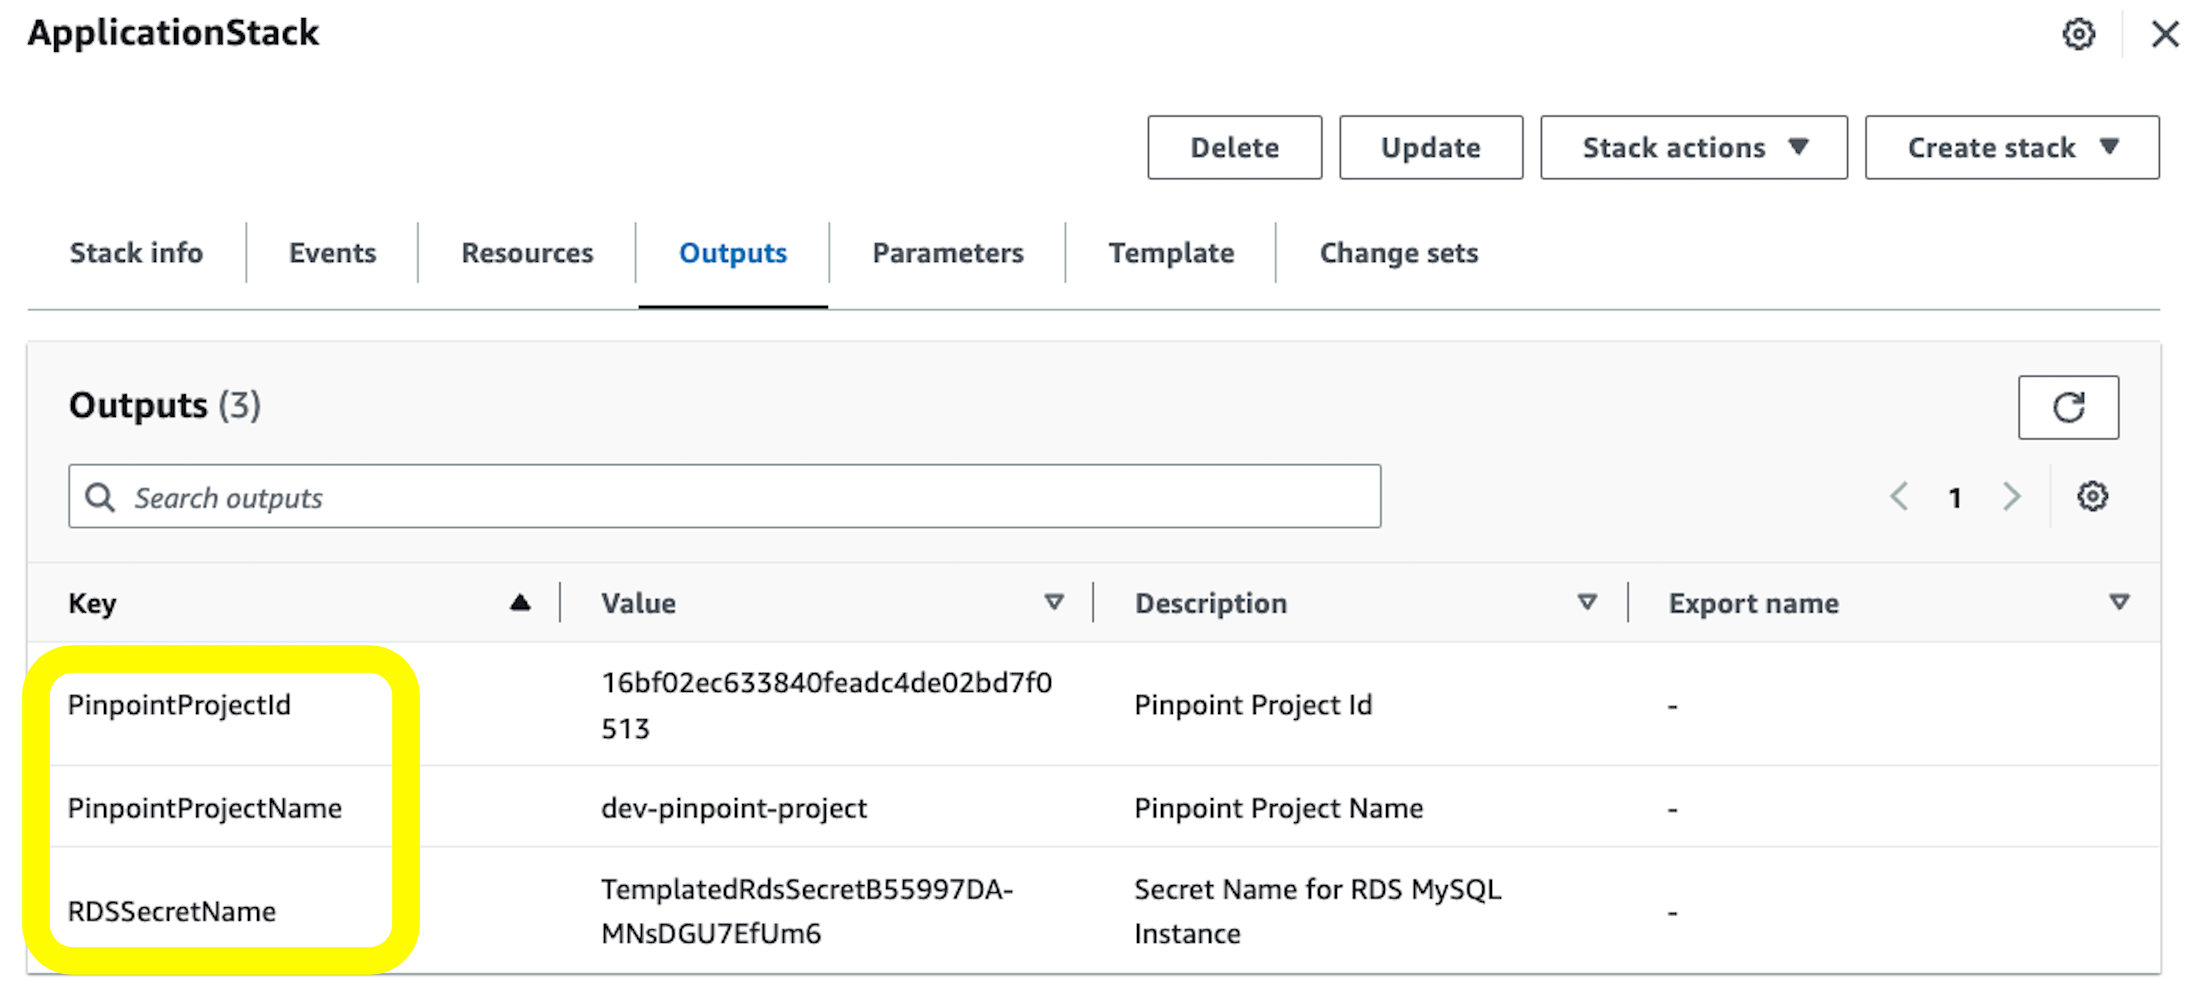
Step 11: Log in to the AWS Console, go to CloudFormation, and see the output of the ApplicationStack:

Fig 7: AWS CloudFormation stack output

Fig 7: AWS CloudFormation stack output

Note the values of PinpointProjectId, PinpointProjectName, and RDSSecretName variables. We’ll use them in the next step to upload our artifacts

Testing The Solution

In this section we will create a full data flow using the below steps:

  1. Ingest data in the customer_tb table within the Amazon RDS MySQL DB instance
  2. Validate that AWS Data Migration Service created task is replicating the changes to the Amazon Kinesis Data Streams
  3. Validate that endpoints are created within Amazon Pinpoint
  4. Create Amazon Pinpoint Segment and Campaign and activate data to Webhook.site endpoint URL

Step 1: Connect to MySQL DB instance and create customer database

    1. Sign in to the AWS Management Console and open the AWS Cloud9 console at https://console.aws.amazon.com/cloud9 
    2. Click Create environment
      • Name: mysql-cloud9-01 (for example)
      • Click Next
      • Environment type: Create a new EC2 instance for environment (direct access)
      • Instance type: t2.micro
      • Timeout: 30 minutes
      • Platform: Amazon Linux 2
      • Network settings under VPC settings select the same VPC where the MySQL DB instance was created. (this is the same VPC and Subnet from step 3.3)
      • Click Next
      • Review and click Create environment
    3. Select the created AWS Cloud9 from the AWS Cloud9 console at https://console.aws.amazon.com/cloud9  and click Open in Cloud9. You will have access to AWS Cloud9 Linux shell.
    4. From Linux shell, update the operating system and :
      sudo yum update -y
    5. From Linux shell, update the operating system and :
      sudo yum install -y mysql
    6. To connect to the created MySQL RDS DB instance, use the below command in the AWS Cloud9 Linux shell:
      mysql -h <<host>> -P 3308 --user=<<username>> --password=<<password>>
      • To get values for dbInstanceIdentifier, username, and password
        • Navigate to the AWS Secrets Manager service
        • Open the secret with the name created by the CDK application
        • Select ‘Reveal secret value’ and copy the respective values and replace in your command
      • After you enter the password for the user, you should see output similar to the following.
      • Welcome to the MariaDB monitor.  Commands end with ; or \g.
        Your MySQL connection id is 27
        Server version: 8.0.32 Source distribution
        Copyright (c) 2000, 2018, Oracle, MariaDB Corporation Ab and others.
        Type 'help;' or '\h' for help. Type '\c' to clear the current input statement.
        MySQL [(none)]>

Step 2: Ingest data in the customer_tb table within the Amazon RDS MySQL DB instance Once the connection to the MySQL DB instance established, using the same AWS Cloud9 Linux shell connected to the MySQL RDS DB execute following commands.

  • Create database pinpoint-test-db:
    CREATE DATABASE `pinpoint-test-db`;
  • Create table customer-tb:
    Use `pinpoint-test-db`;
    CREATE TABLE `customer_tb` (`userid` int NOT NULL,
                                `email` varchar(150) DEFAULT NULL,
                                `language` varchar(45) DEFAULT NULL,
                                `favourites` varchar(250) DEFAULT NULL,
                                PRIMARY KEY (`userid`);
  • You can verify the schema using the below SQL command:
  1. DESCRIBE `pinpoint-test-db`.customer_tb;
    Fig 8: Verify schema for customer_db table

    Fig 8: Verify schema for customer_db table

    • Insert records in customer_tb table:
    Use `pinpoint-test-db`;
    insert into customer_tb values (1,'[email protected]','english','football');
    insert into customer_tb values (2,'[email protected]','english','basketball');
    insert into customer_tb values (3,'[email protected]','french','football');
    insert into customer_tb values (4,'[email protected]','french','football');
    insert into customer_tb values (5,'[email protected]','french','basketball');
    insert into customer_tb values (6,'[email protected]','french','football');
    insert into customer_tb values (7,'[email protected]','french',null);
    insert into customer_tb values (8,'[email protected]','english','football');
    insert into customer_tb values (9,'[email protected]','english','football');
    insert into customer_tb values (10,'[email protected]','english',null);
    • Verify records in customer_tb table:
    select * from `pinpoint-test-db`.`customer_tb`;
    Fig 9: Verify data for customer_db table

    Fig 9: Verify data for customer_db table

    Step 3: Validate that AWS Data Migration Service created task is replicating the changes to the Amazon Kinesis Data Streams

      1. Sign in to the AWS Management Console and open the AWS DMS console at https://console.aws.amazon.com/dms/v2 
      2. From the navigation panel, choose Database migration tasks.
      3. Click on the created task created by CDK code ‘dmsreplicationtask-*’
      4. Start the replication task

        Fig 10: Starting AWS DMS Replication Task

        Fig 10: Starting AWS DMS Replication Task

      5. Make sure that Status is Replication ongoing

        Fig 11: AWS DMS Replication statistics

        Fig 11: AWS DMS Replication statistics

      6. Navigate to Table Statistics and make sure that the number of Inserts is equal to 10 and Load state is Table completed*

        Fig 12: AWS DMS Replication statistics

        Fig 12: AWS DMS Replication statistics

    Step 4: Validate that endpoints are created within Amazon Pinpoint

    1. Sign in to the AWS Management Console and open the Amazon Pinpoint console at https://console.aws.amazon.com/pinpoint/ 
    2. Click on Amazon Pinpoint Project Demo created by CDK stack “dev-pinpoint-project”
    3. From the left menu, click on Analytics and validate that the Active targetable endpoints are equal to 10 as shown below:
    Fig 13: Amazon Pinpoint endpoint summary

    Fig 13: Amazon Pinpoint endpoint summary

    Step 5: Create Amazon Pinpoint Segment and Campaign

    Step 5.1: Create Amazon Pinpoint Segment

    • Sign in to the AWS Management Console and open the Amazon Pinpoint console at https://console.aws.amazon.com/pinpoint/ 
    • Click on Amazon Pinpoint Project Demo created by CDK stack “dev-pinpoint-project”
    • from the left menu, click on Segments and click Create a segment
    • create Segment using the below configurations:
      • Name: English Speakers
      • Under criteria:
    • Attribute: Language
    • Operator: Conatins
    • Value: english
    Fig 14: Amazon Pinpoint segment summary

    Fig 14: Amazon Pinpoint segment summary

    • Click create segment

    Step 5.2: Create Amazon Pinpoint Campaign

    • from the left menu, click on Campaigns and click Create a campaign
    • set the Campaign name to test campaign and select Custom option for Channel as shown below:
    Fig 15: Amazon Pinpoint create campaign

    Fig 15: Amazon Pinpoint create campaign

    • Click Next
    • Select English Speakers from Segment as shown below and click Next:
    Fig 16: Amazon Pinpoint segment

    Fig 16: Amazon Pinpoint segment

    • Choose Lambda function channel type and select outbound lambda function with name pattern as ApplicationStack-lambdaoutboundfunction* from the dropdown as shown below:
    Fig 17: Amazon Pinpoint message creation

    Fig 17: Amazon Pinpoint message creation

    • Click Next
    • Choose At a specific time option and immediately to send the campaign as show below:
    Fig 18: Amazon Pinpoint campaign scheduling

    Fig 18: Amazon Pinpoint campaign scheduling

    If you push more messages or records into Amazon RDS (from step 2.4), you will need to create a new campaign (from step 4.2) to process the new messages.

    • Click Next, review the configuration and click Launch campaign.
    • Navigate to dev-pinpoint-project and select the campaign created in previous step. You should see status as ‘Complete’
    Fig 19: Amazon Pinpoint campaign processing status

    Fig 19: Amazon Pinpoint campaign processing status

    • Navigate to dev-pinpoint-project dashboard and select your campaign in ‘Campaign metrics’ dashboard, you will see the statistics for the processing.
    Fig 20: Amazon Pinpoint campaign metrics

    Fig 20: Amazon Pinpoint campaign metrics

    Accomplishments

    This is a quick summary of what we accomplished:

    1. Created an Amazon RDS MySQL DB instance and define customer_tb table schema
    2. Created an Amazon Kinesis Data Stream
    3. Replicated database changes from the Amazon RDS MySQL DB to Amazon Kinesis Data Stream
    4. Created an AWS Lambda function triggered by Amazon Kinesis Data Stream to ingest database records in Amazon Pinpoints as User endpoints using AWS SDK
    5. Created an Amazon Pinpoint Project, segment and campaign
    6. Created an AWS Lambda function as custom channel for Amazon Pinpoint campaign
    7. Tested end-to-end data flow from Amazon RDS MySQL DB instance to third party endpoint

    Next Steps

    You have now gained a good understanding of Amazon Pinpoint agnostic data flow but there are still many areas left for exploration. What this workshop hasn’t covered is the operation of other communication channels such as Email, SMS, Push notification and Voice outbound. You can enable the channels that are pertinent to your use case and send messages using campaigns or journeys.

    Clean Up

    Make sure that you clean up all of the other AWS resources that you created in the AWS CDK Stack deployment. You can delete these resources via the AWS CDK Destroy command as follows or the CloudFormation console.

    To destroy the resources using AWS CDK, follow these steps:

    • Follow Steps 1-5 from the ‘Launching your CDK Stack’ section.
    • Destroy the app by executing the following command:
    cdk destroy

    Summary

    In this post, you have now gained a good understanding of Amazon Pinpoint flexible real-time data flow. By implementing the steps detailed in this blog post, you can achieve a seamless integration of your customer data from Amazon RDS MySQL database to Amazon Pinpoint where you can leverage segments and campaigns to activate data using custom channels to third-party services via API. The demonstrated use case focuses on Amazon RDS MySQL database as a data source. However, there are still many areas left for exploration. What this post hasn’t covered is the operation of integrating customer data from other type of data sources such as MongoDB, Microsoft SQL Server, Google Cloud, etc. Also, other communication channels such as Email, SMS, Push notification and Voice outbound can be used in the activation layer. You can enable the channels that are pertinent to your use case and send messages using campaigns or journeys, and get a complete view of their customers across all touchpoints and can lead to less relevant marketing campaigns.

    About the Authors

  2. Bret Pontillo is a Senior Data Architect with AWS Professional Services Analytics Practice. He helps customers implement big data and analytics solutions. Outside of work, he enjoys spending time with family, traveling, and trying new food.
    Rushabh Lokhande is a Data & ML Engineer with AWS Professional Services Analytics Practice. He helps customers implement big data, machine learning, and analytics solutions. Outside of work, he enjoys spending time with family, reading, running, and golf.
    Ghandi Nader is a Senior Partner Solution Architect focusing on the Adtech and Martech industry. He helps customers and partners innovate and align with the market trends related to the industry. Outside of work, he enjoys spending time cycling and watching formula one.

Simplify AWS Glue job orchestration and monitoring with Amazon MWAA

Post Syndicated from Rushabh Lokhande original https://aws.amazon.com/blogs/big-data/simplify-aws-glue-job-orchestration-and-monitoring-with-amazon-mwaa/

Organizations across all industries have complex data processing requirements for their analytical use cases across different analytics systems, such as data lakes on AWS, data warehouses (Amazon Redshift), search (Amazon OpenSearch Service), NoSQL (Amazon DynamoDB), machine learning (Amazon SageMaker), and more. Analytics professionals are tasked with deriving value from data stored in these distributed systems to create better, secure, and cost-optimized experiences for their customers. For example, digital media companies seek to combine and process datasets in internal and external databases to build unified views of their customer profiles, spur ideas for innovative features, and increase platform engagement.

In these scenarios, customers looking for a serverless data integration offering use AWS Glue as a core component for processing and cataloging data. AWS Glue is well integrated with AWS services and partner products, and provides low-code/no-code extract, transform, and load (ETL) options to enable analytics, machine learning (ML), or application development workflows. AWS Glue ETL jobs may be one component in a more complex pipeline. Orchestrating the run of and managing dependencies between these components is a key capability in a data strategy. Amazon Managed Workflows for Apache Airflows (Amazon MWAA) orchestrates data pipelines using distributed technologies including on-premises resources, AWS services, and third-party components.

In this post, we show how to simplify monitoring an AWS Glue job orchestrated by Airflow using the latest features of Amazon MWAA.

Overview of solution

This post discusses the following:

  • How to upgrade an Amazon MWAA environment to version 2.4.3.
  • How to orchestrate an AWS Glue job from an Airflow Directed Acyclic Graph (DAG).
  • The Airflow Amazon provider package’s observability enhancements in Amazon MWAA. You can now consolidate run logs of AWS Glue jobs on the Airflow console to simplify troubleshooting data pipelines. The Amazon MWAA console becomes a single reference to monitor and analyze AWS Glue job runs. Previously, support teams needed to access the AWS Management Console and take manual steps for this visibility. This feature is available by default from Amazon MWAA version 2.4.3.

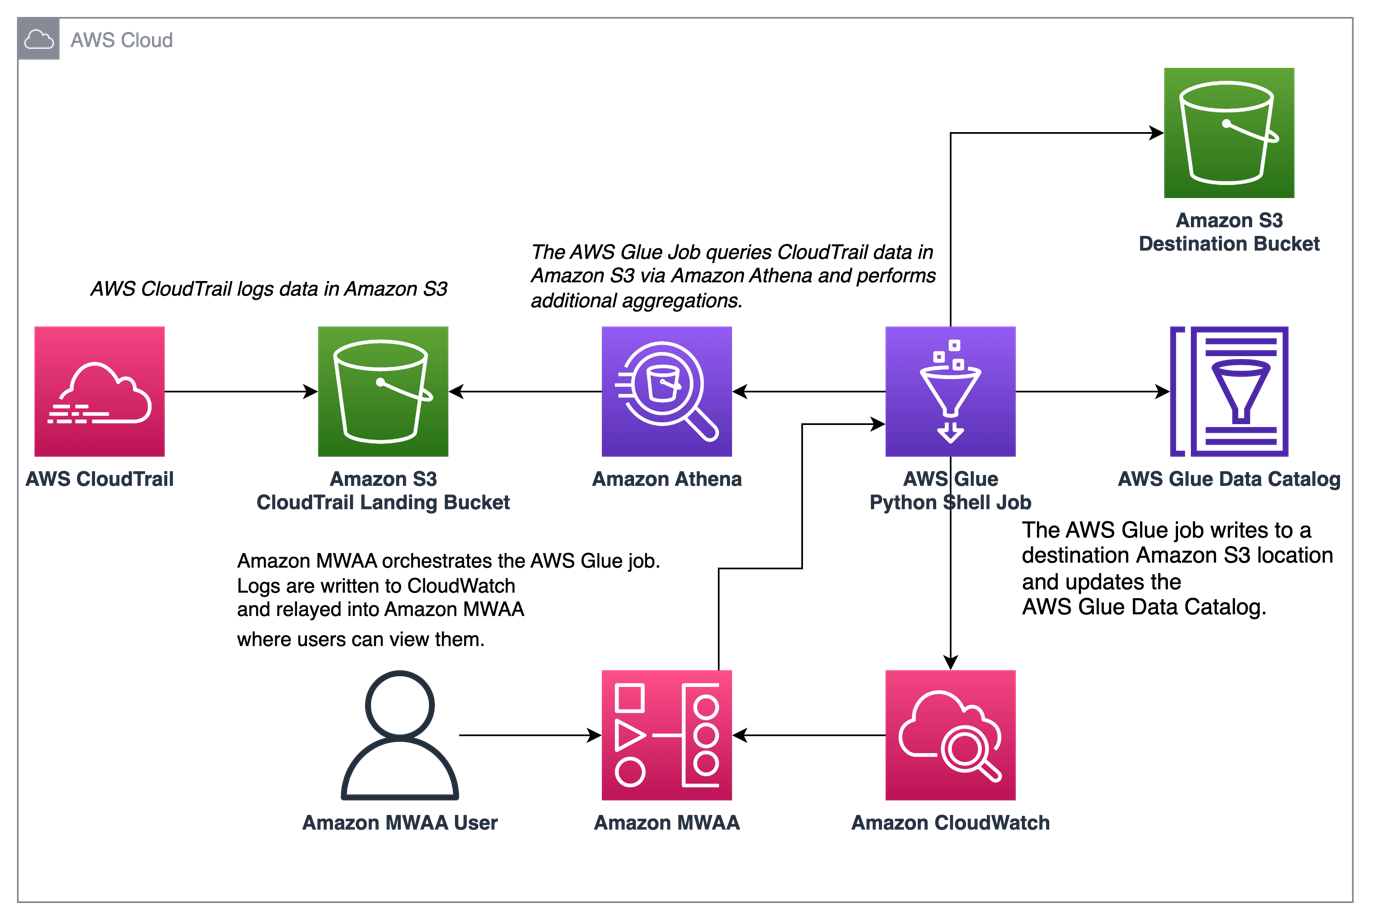
The following diagram illustrates our solution architecture.

Prerequisites

You need the following prerequisites:

Set up the Amazon MWAA environment

For instructions on creating your environment, refer to Create an Amazon MWAA environment. For existing users, we recommend upgrading to version 2.4.3 to take advantage of the observability enhancements featured in this post.

The steps to upgrade Amazon MWAA to version 2.4.3 differ depending on whether the current version is 1.10.12 or 2.2.2. We discuss both options in this post.

Prerequisites for setting up an Amazon MWAA environment

You must meet the following prerequisites:

Upgrade from version 1.10.12 to 2.4.3

If you’re using Amazon MWAA version 1.10.12, refer to Migrating to a new Amazon MWAA environment to upgrade to 2.4.3.

Upgrade from version 2.0.2 or 2.2.2 to 2.4.3

If you’re using Amazon MWAA environment version 2.2.2 or lower, complete the following steps:

  1. Create a requirements.txt for any custom dependencies with specific versions required for your DAGs.
  2. Upload the file to Amazon S3 in the appropriate location where the Amazon MWAA environment points to the requirements.txt for installing dependencies.
  3. Follow the steps in Migrating to a new Amazon MWAA environment and select version 2.4.3.

Update your DAGs

Customers who upgraded from an older Amazon MWAA environment may need to make updates to existing DAGs. In Airflow version 2.4.3, the Airflow environment will use the Amazon provider package version 6.0.0 by default. This package may include some potentially breaking changes, such as changes to operator names. For example, the AWSGlueJobOperator has been deprecated and replaced with the GlueJobOperator. To maintain compatibility, update your Airflow DAGs by replacing any deprecated or unsupported operators from previous versions with the new ones. Complete the following steps:

  1. Navigate to Amazon AWS Operators.
  2. Select the appropriate version installed in your Amazon MWAA instance (6.0.0. by default) to find a list of supported Airflow operators.
  3. Make the necessary changes in the existing DAG code and upload the modified files to the DAG location in Amazon S3.

Orchestrate the AWS Glue job from Airflow

This section covers the details of orchestrating an AWS Glue job within Airflow DAGs. Airflow eases the development of data pipelines with dependencies between heterogeneous systems such as on-premises processes, external dependencies, other AWS services, and more.

Orchestrate CloudTrail log aggregation with AWS Glue and Amazon MWAA

In this example, we go through a use case of using Amazon MWAA to orchestrate an AWS Glue Python Shell job that persists aggregated metrics based on CloudTrail logs.

CloudTrail enables visibility into AWS API calls that are being made in your AWS account. A common use case with this data would be to gather usage metrics on principals acting on your account’s resources for auditing and regulatory needs.

As CloudTrail events are being logged, they are delivered as JSON files in Amazon S3, which aren’t ideal for analytical queries. We want to aggregate this data and persist it as Parquet files to allow for optimal query performance. As an initial step, we can use Athena to do the initial querying of the data before doing additional aggregations in our AWS Glue job. For more information about creating an AWS Glue Data Catalog table, refer to Creating the table for CloudTrail logs in Athena using partition projection data. After we’ve explored the data via Athena and decided what metrics we want to retain in aggregate tables, we can create an AWS Glue job.

Create an CloudTrail table in Athena

First, we need to create a table in our Data Catalog that allows CloudTrail data to be queried via Athena. The following sample query creates a table with two partitions on the Region and date (called snapshot_date). Be sure to replace the placeholders for your CloudTrail bucket, AWS account ID, and CloudTrail table name:

create external table if not exists `<<<CLOUDTRAIL_TABLE_NAME>>>`(
  `eventversion` string comment 'from deserializer', 
  `useridentity` struct<type:string,principalid:string,arn:string,accountid:string,invokedby:string,accesskeyid:string,username:string,sessioncontext:struct<attributes:struct<mfaauthenticated:string,creationdate:string>,sessionissuer:struct<type:string,principalid:string,arn:string,accountid:string,username:string>>> comment 'from deserializer', 
  `eventtime` string comment 'from deserializer', 
  `eventsource` string comment 'from deserializer', 
  `eventname` string comment 'from deserializer', 
  `awsregion` string comment 'from deserializer', 
  `sourceipaddress` string comment 'from deserializer', 
  `useragent` string comment 'from deserializer', 
  `errorcode` string comment 'from deserializer', 
  `errormessage` string comment 'from deserializer', 
  `requestparameters` string comment 'from deserializer', 
  `responseelements` string comment 'from deserializer', 
  `additionaleventdata` string comment 'from deserializer', 
  `requestid` string comment 'from deserializer', 
  `eventid` string comment 'from deserializer', 
  `resources` array<struct<arn:string,accountid:string,type:string>> comment 'from deserializer', 
  `eventtype` string comment 'from deserializer', 
  `apiversion` string comment 'from deserializer', 
  `readonly` string comment 'from deserializer', 
  `recipientaccountid` string comment 'from deserializer', 
  `serviceeventdetails` string comment 'from deserializer', 
  `sharedeventid` string comment 'from deserializer', 
  `vpcendpointid` string comment 'from deserializer')
PARTITIONED BY ( 
  `region` string,
  `snapshot_date` string)
ROW FORMAT SERDE 
  'com.amazon.emr.hive.serde.CloudTrailSerde' 
STORED AS INPUTFORMAT 
  'com.amazon.emr.cloudtrail.CloudTrailInputFormat' 
OUTPUTFORMAT 
  'org.apache.hadoop.hive.ql.io.HiveIgnoreKeyTextOutputFormat'
LOCATION
  's3://<<<CLOUDTRAIL_BUCKET>>>/AWSLogs/<<<ACCOUNT_ID>>>/CloudTrail/'
TBLPROPERTIES (
  'projection.enabled'='true', 
  'projection.region.type'='enum',
  'projection.region.values'='us-east-2,us-east-1,us-west-1,us-west-2,af-south-1,ap-east-1,ap-south-1,ap-northeast-3,ap-northeast-2,ap-southeast-1,ap-southeast-2,ap-northeast-1,ca-central-1,eu-central-1,eu-west-1,eu-west-2,eu-south-1,eu-west-3,eu-north-1,me-south-1,sa-east-1',
  'projection.snapshot_date.format'='yyyy/mm/dd', 
  'projection.snapshot_date.interval'='1', 
  'projection.snapshot_date.interval.unit'='days', 
  'projection.snapshot_date.range'='2020/10/01,now', 
  'projection.snapshot_date.type'='date',
  'storage.location.template'='s3://<<<CLOUDTRAIL_BUCKET>>>/AWSLogs/<<<ACCOUNT_ID>>>/CloudTrail/${region}/${snapshot_date}')

Run the preceding query on the Athena console, and note the table name and AWS Glue Data Catalog database where it was created. We use these values later in the Airflow DAG code.

Sample AWS Glue job code

The following code is a sample AWS Glue Python Shell job that does the following:

  • Takes arguments (which we pass from our Amazon MWAA DAG) on what day’s data to process
  • Uses the AWS SDK for Pandas to run an Athena query to do the initial filtering of the CloudTrail JSON data outside AWS Glue
  • Uses Pandas to do simple aggregations on the filtered data
  • Outputs the aggregated data to the AWS Glue Data Catalog in a table
  • Uses logging during processing, which will be visible in Amazon MWAA
import awswrangler as wr
import pandas as pd
import sys
import logging
from awsglue.utils import getResolvedOptions
from datetime import datetime, timedelta

# Logging setup, redirects all logs to stdout
LOGGER = logging.getLogger()
formatter = logging.Formatter('%(asctime)s.%(msecs)03d %(levelname)s %(module)s - %(funcName)s: %(message)s')
streamHandler = logging.StreamHandler(sys.stdout)
streamHandler.setFormatter(formatter)
LOGGER.addHandler(streamHandler)
LOGGER.setLevel(logging.INFO)

LOGGER.info(f"Passed Args :: {sys.argv}")

sql_query_template = """
select
region,
useridentity.arn,
eventsource,
eventname,
useragent

from "{cloudtrail_glue_db}"."{cloudtrail_table}"
where snapshot_date='{process_date}'
and region in ('us-east-1','us-east-2')
"""

required_args = ['CLOUDTRAIL_GLUE_DB',
                'CLOUDTRAIL_TABLE',
                'TARGET_BUCKET',
                'TARGET_DB',
                'TARGET_TABLE',
                'ACCOUNT_ID']
arg_keys = [*required_args, 'PROCESS_DATE'] if '--PROCESS_DATE' in sys.argv else required_args
JOB_ARGS = getResolvedOptions ( sys.argv, arg_keys)

LOGGER.info(f"Parsed Args :: {JOB_ARGS}")

# if process date was not passed as an argument, process yesterday's data
process_date = (
    JOB_ARGS['PROCESS_DATE']
    if JOB_ARGS.get('PROCESS_DATE','NONE') != "NONE" 
    else (datetime.today() - timedelta(days=1)).strftime("%Y-%m-%d") 
)

LOGGER.info(f"Taking snapshot for :: {process_date}")

RAW_CLOUDTRAIL_DB = JOB_ARGS['CLOUDTRAIL_GLUE_DB']
RAW_CLOUDTRAIL_TABLE = JOB_ARGS['CLOUDTRAIL_TABLE']
TARGET_BUCKET = JOB_ARGS['TARGET_BUCKET']
TARGET_DB = JOB_ARGS['TARGET_DB']
TARGET_TABLE = JOB_ARGS['TARGET_TABLE']
ACCOUNT_ID = JOB_ARGS['ACCOUNT_ID']

final_query = sql_query_template.format(
    process_date=process_date.replace("-","/"),
    cloudtrail_glue_db=RAW_CLOUDTRAIL_DB,
    cloudtrail_table=RAW_CLOUDTRAIL_TABLE
)

LOGGER.info(f"Running Query :: {final_query}")

raw_cloudtrail_df = wr.athena.read_sql_query(
    sql=final_query,
    database=RAW_CLOUDTRAIL_DB,
    ctas_approach=False,
    s3_output=f"s3://{TARGET_BUCKET}/athena-results",
)

raw_cloudtrail_df['ct']=1

agg_df = raw_cloudtrail_df.groupby(['arn','region','eventsource','eventname','useragent'],as_index=False).agg({'ct':'sum'})
agg_df['snapshot_date']=process_date

LOGGER.info(agg_df.info(verbose=True))

upload_path = f"s3://{TARGET_BUCKET}/{TARGET_DB}/{TARGET_TABLE}"

if not agg_df.empty:
    LOGGER.info(f"Upload to {upload_path}")
    try:
        response = wr.s3.to_parquet(
            df=agg_df,
            path=upload_path,
            dataset=True,
            database=TARGET_DB,
            table=TARGET_TABLE,
            mode="overwrite_partitions",
            schema_evolution=True,
            partition_cols=["snapshot_date"],
            compression="snappy",
            index=False
        )
        LOGGER.info(response)
    except Exception as exc:
        LOGGER.error("Uploading to S3 failed")
        LOGGER.exception(exc)
        raise exc
else:
    LOGGER.info(f"Dataframe was empty, nothing to upload to {upload_path}")

The following are some key advantages in this AWS Glue job:

  • We use an Athena query to ensure initial filtering is done outside of our AWS Glue job. As such, a Python Shell job with minimal compute is still sufficient for aggregating a large CloudTrail dataset.
  • We ensure the analytics library-set option is turned on when creating our AWS Glue job to use the AWS SDK for Pandas library.

Create an AWS Glue job

Complete the following steps to create your AWS Glue job:

  1. Copy the script in the preceding section and save it in a local file. For this post, the file is called script.py.
  2. On the AWS Glue console, choose ETL jobs in the navigation pane.
  3. Create a new job and select Python Shell script editor.
  4. Select Upload and edit an existing script and upload the file you saved locally.
  5. Choose Create.

  1. On the Job details tab, enter a name for your AWS Glue job.
  2. For IAM role, choose an existing role or create a new role that has the required permissions for Amazon S3, AWS Glue, and Athena. The role needs to query the CloudTrail table you created earlier and write to an output location.

You can use the following sample policy code. Replace the placeholders with your CloudTrail logs bucket, output table name, output AWS Glue database, output S3 bucket, CloudTrail table name, AWS Glue database containing the CloudTrail table, and your AWS account ID.

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Action": [
                "s3:List*",
                "s3:Get*"
            ],
            "Resource": [
                "arn:aws:s3:::<<<CLOUDTRAIL_LOGS_BUCKET>>>/*",
                "arn:aws:s3:::<<<CLOUDTRAIL_LOGS_BUCKET>>>*"
            ],
            "Effect": "Allow",
            "Sid": "GetS3CloudtrailData"
        },
        {
            "Action": [
                "glue:Get*",
                "glue:BatchGet*"
            ],
            "Resource": [
                "arn:aws:glue:us-east-1:<<<YOUR_AWS_ACCT_ID>>>:catalog",
                "arn:aws:glue:us-east-1:<<<YOUR_AWS_ACCT_ID>>>:database/<<<GLUE_DB_WITH_CLOUDTRAIL_TABLE>>>",
                "arn:aws:glue:us-east-1:<<<YOUR_AWS_ACCT_ID>>>:table/<<<GLUE_DB_WITH_CLOUDTRAIL_TABLE>>>/<<<CLOUDTRAIL_TABLE>>>*"
            ],
            "Effect": "Allow",
            "Sid": "GetGlueCatalogCloudtrailData"
        },
        {
            "Action": [
                "s3:PutObject*",
                "s3:Abort*",
                "s3:DeleteObject*",
                "s3:GetObject*",
                "s3:GetBucket*",
                "s3:List*",
                "s3:Head*"
            ],
            "Resource": [
                "arn:aws:s3:::<<<OUTPUT_S3_BUCKET>>>",
                "arn:aws:s3:::<<<OUTPUT_S3_BUCKET>>>/<<<OUTPUT_GLUE_DB>>>/<<<OUTPUT_TABLE_NAME>>>/*"
            ],
            "Effect": "Allow",
            "Sid": "WriteOutputToS3"
        },
        {
            "Action": [
                "glue:CreateTable",
                "glue:CreatePartition",
                "glue:UpdatePartition",
                "glue:UpdateTable",
                "glue:DeleteTable",
                "glue:DeletePartition",
                "glue:BatchCreatePartition",
                "glue:BatchDeletePartition",
                "glue:Get*",
                "glue:BatchGet*"
            ],
            "Resource": [
                "arn:aws:glue:us-east-1:<<<YOUR_AWS_ACCT_ID>>>:catalog",
                "arn:aws:glue:us-east-1:<<<YOUR_AWS_ACCT_ID>>>:database/<<<OUTPUT_GLUE_DB>>>",
                "arn:aws:glue:us-east-1:<<<YOUR_AWS_ACCT_ID>>>:table/<<<OUTPUT_GLUE_DB>>>/<<<OUTPUT_TABLE_NAME>>>*"
            ],
            "Effect": "Allow",
            "Sid": "AllowOutputToGlue"
        },
        {
            "Action": [
                "logs:CreateLogGroup",
                "logs:CreateLogStream",
                "logs:PutLogEvents"
            ],
            "Resource": "arn:aws:logs:*:*:/aws-glue/*",
            "Effect": "Allow",
            "Sid": "LogsAccess"
        },
        {
            "Action": [
                "s3:GetObject*",
                "s3:GetBucket*",
                "s3:List*",
                "s3:DeleteObject*",
                "s3:PutObject",
                "s3:PutObjectLegalHold",
                "s3:PutObjectRetention",
                "s3:PutObjectTagging",
                "s3:PutObjectVersionTagging",
                "s3:Abort*"
            ],
            "Resource": [
                "arn:aws:s3:::<<<ATHENA_RESULTS_BUCKET>>>",
                "arn:aws:s3:::<<<ATHENA_RESULTS_BUCKET>>>/*"
            ],
            "Effect": "Allow",
            "Sid": "AccessToAthenaResults"
        },
        {
            "Action": [
                "athena:StartQueryExecution",
                "athena:StopQueryExecution",
                "athena:GetDataCatalog",
                "athena:GetQueryResults",
                "athena:GetQueryExecution"
            ],
            "Resource": [
                "arn:aws:glue:us-east-1:<<<YOUR_AWS_ACCT_ID>>>:catalog",
                "arn:aws:athena:us-east-1:<<<YOUR_AWS_ACCT_ID>>>:datacatalog/AwsDataCatalog",
                "arn:aws:athena:us-east-1:<<<YOUR_AWS_ACCT_ID>>>:workgroup/primary"
            ],
            "Effect": "Allow",
            "Sid": "AllowAthenaQuerying"
        }
    ]
}

For Python version, choose Python 3.9.

  1. Select Load common analytics libraries.
  2. For Data processing units, choose 1 DPU.
  3. Leave the other options as default or adjust as needed.

  1. Choose Save to save your job configuration.

Configure an Amazon MWAA DAG to orchestrate the AWS Glue job

The following code is for a DAG that can orchestrate the AWS Glue job that we created. We take advantage of the following key features in this DAG:

"""Sample DAG"""
import airflow.utils
from airflow.providers.amazon.aws.operators.glue import GlueJobOperator
from airflow import DAG
from datetime import timedelta
import airflow.utils

# allow backfills via DAG run parameters
process_date = '{{ dag_run.conf.get("process_date") if dag_run.conf.get("process_date") else "NONE" }}'

dag = DAG(
    dag_id = "CLOUDTRAIL_LOGS_PROCESSING",
    default_args = {
        'depends_on_past':False, 
        'start_date':airflow.utils.dates.days_ago(0),
        'retries':1,
        'retry_delay':timedelta(minutes=5),
        'catchup': False
    },
    schedule_interval = None, # None for unscheduled or a cron expression - E.G. "00 12 * * 2" - at 12noon Tuesday
    dagrun_timeout = timedelta(minutes=30),
    max_active_runs = 1,
    max_active_tasks = 1 # since there is only one task in our DAG
)

## Log ingest. Assumes Glue Job is already created
glue_ingestion_job = GlueJobOperator(
    task_id="<<<some-task-id>>>",
    job_name="<<<GLUE_JOB_NAME>>>",
    script_args={
        "--ACCOUNT_ID":"<<<YOUR_AWS_ACCT_ID>>>",
        "--CLOUDTRAIL_GLUE_DB":"<<<GLUE_DB_WITH_CLOUDTRAIL_TABLE>>>",
        "--CLOUDTRAIL_TABLE":"<<<CLOUDTRAIL_TABLE>>>",
        "--TARGET_BUCKET": "<<<OUTPUT_S3_BUCKET>>>",
        "--TARGET_DB": "<<<OUTPUT_GLUE_DB>>>", # should already exist
        "--TARGET_TABLE": "<<<OUTPUT_TABLE_NAME>>>",
        "--PROCESS_DATE": process_date
    },
    region_name="us-east-1",
    dag=dag,
    verbose=True
)

glue_ingestion_job

Increase observability of AWS Glue jobs in Amazon MWAA

The AWS Glue jobs write logs to Amazon CloudWatch. With the recent observability enhancements to Airflow’s Amazon provider package, these logs are now integrated with Airflow task logs. This consolidation provides Airflow users with end-to-end visibility directly in the Airflow UI, eliminating the need to search in CloudWatch or the AWS Glue console.

To use this feature, ensure the IAM role attached to the Amazon MWAA environment has the following permissions to retrieve and write the necessary logs:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": [
        "logs:CreateLogGroup",
        "logs:CreateLogStream",
        "logs:PutLogEvents",
        "logs:GetLogEvents",
        "logs:GetLogRecord",
        "logs:DescribeLogStreams",
        "logs:FilterLogEvents",
        "logs:GetLogGroupFields",
        "logs:GetQueryResults",
        
      ],
      "Resource": [
        "arn:aws:logs:*:*:log-group:airflow-243-<<<Your environment name>>>-*"--Your Amazon MWAA Log Stream Name
      ]
    }
  ]
}

If verbose=true, the AWS Glue job run logs show in the Airflow task logs. The default is false. For more information, refer to Parameters.

When enabled, the DAGs read from the AWS Glue job’s CloudWatch log stream and relay them to the Airflow DAG AWS Glue job step logs. This provides detailed insights into an AWS Glue job’s run in real time via the DAG logs. Note that AWS Glue jobs generate an output and error CloudWatch log group based on the job’s STDOUT and STDERR, respectively. All logs in the output log group and exception or error logs from the error log group are relayed into Amazon MWAA.

AWS admins can now limit a support team’s access to only Airflow, making Amazon MWAA the single pane of glass on job orchestration and job health management. Previously, users needed to check AWS Glue job run status in the Airflow DAG steps and retrieve the job run identifier. They then needed to access the AWS Glue console to find the job run history, search for the job of interest using the identifier, and finally navigate to the job’s CloudWatch logs to troubleshoot.

Create the DAG

To create the DAG, complete the following steps:

  1. Save the preceding DAG code to a local .py file, replacing the indicated placeholders.

The values for your AWS account ID, AWS Glue job name, AWS Glue database with CloudTrail table, and CloudTrail table name should already be known. You can adjust the output S3 bucket, output AWS Glue database, and output table name as needed, but make sure the AWS Glue job’s IAM role that you used earlier is configured accordingly.

  1. On the Amazon MWAA console, navigate to your environment to see where the DAG code is stored.

The DAGs folder is the prefix within the S3 bucket where your DAG file should be placed.

  1. Upload your edited file there.

  1. Open the Amazon MWAA console to confirm that the DAG appears in the table.

Run the DAG

To run the DAG, complete the following steps:

  1. Choose from the following options:
    • Trigger DAG – This causes yesterday’s data to be used as the data to process
    • Trigger DAG w/ config – With this option, you can pass in a different date, potentially for backfills, which is retrieved using dag_run.conf in the DAG code and then passed into the AWS Glue job as a parameter

The following screenshot shows the additional configuration options if you choose Trigger DAG w/ config.

  1. Monitor the DAG as it runs.
  2. When the DAG is complete, open the run’s details.

On the right pane, you can view the logs, or choose Task Instance Details for a full view.

  1. View the AWS Glue job output logs in Amazon MWAA without using the AWS Glue console thanks to the GlueJobOperator verbose flag.

The AWS Glue job will have written results to the output table you specified.

  1. Query this table via Athena to confirm it was successful.

Summary

Amazon MWAA now provides a single place to track AWS Glue job status and enables you to use the Airflow console as the single pane of glass for job orchestration and health management. In this post, we walked through the steps to orchestrate AWS Glue jobs via Airflow using GlueJobOperator. With the new observability enhancements, you can seamlessly troubleshoot AWS Glue jobs in a unified experience. We also demonstrated how to upgrade your Amazon MWAA environment to a compatible version, update dependencies, and change the IAM role policy accordingly.

For more information about common troubleshooting steps, refer to Troubleshooting: Creating and updating an Amazon MWAA environment. For in-depth details of migrating to an Amazon MWAA environment, refer to Upgrading from 1.10 to 2. To learn about the open-source code changes for increased observability of AWS Glue jobs in the Airflow Amazon provider package, refer to the relay logs from AWS Glue jobs.

Finally, we recommend visiting the AWS Big Data Blog for other material on analytics, ML, and data governance on AWS.


About the Authors

Rushabh Lokhande is a Data & ML Engineer with the AWS Professional Services Analytics Practice. He helps customers implement big data, machine learning, and analytics solutions. Outside of work, he enjoys spending time with family, reading, running, and golf.

Ryan Gomes is a Data & ML Engineer with the AWS Professional Services Analytics Practice. He is passionate about helping customers achieve better outcomes through analytics and machine learning solutions in the cloud. Outside of work, he enjoys fitness, cooking, and spending quality time with friends and family.

Vishwa Gupta is a Senior Data Architect with the AWS Professional Services Analytics Practice. He helps customers implement big data and analytics solutions. Outside of work, he enjoys spending time with family, traveling, and trying new food.