Tag Archives: Digital forensics

A framework for securely collecting forensic artifacts into S3 buckets

Post Syndicated from Jason Garman original https://aws.amazon.com/blogs/security/a-framework-for-securely-collecting-forensic-artifacts-into-s3-buckets/

When customers experience a security incident, they need to acquire forensic artifacts to identify root cause, extract indicators of compromise (IoCs), and validate remediation efforts. NIST 800-86, Guide to Integrating Forensic Techniques into Incident Response, defines digital forensics as a process comprised of four basic phases: collection, examination, analysis, and reporting. This blog post focuses on the first phase—collection—and provides best practices for implementing least privilege during the forensic evidence collection processes that collect evidence and store the artifacts in Amazon Simple Storage Service (Amazon S3) buckets. The architecture presented in this post can be used to collect forensic evidence from both Amazon Web Services (AWS) and non-AWS compute resources.

It’s important to consider the security of the forensic artifact collection process because it involves communicating with potentially compromised resources. The collection methodology itself should be designed to avoid adding additional risks to infrastructure or other forensic investigation processes. At the same time, the collection of forensic artifacts requires the use of specialized tools that are difficult to change or adapt to new security requirements.

This post outlines factors that you should consider when creating an evidence collection capability and introduces an architecture that implements the best practices for least privilege and integrating with (instead of changing or adapting) existing forensic tools that support uploading artifacts to S3 buckets by using AWS security credentials.

Solution architecture

The architecture presented in this post demonstrates the following AWS best practices:

  1. Least privilege – Use AWS Identity and Access Management (IAM) policies to provide least privilege access to upload forensic artifacts to an S3 location dedicated to a specific forensic collection task. The locked down credentials cannot be used to view or modify any other forensic collections.
  2. Time-limited credentials – Use AWS Security Token Service (AWS STS) to provide time limited credentials, reducing the potential for an unauthorized user to abuse credentials while they’re visible on the target machine during the artifact collection process.
  3. Compatibility with third-party tools – Forensic tools are specialized and changing a forensic collection process to adapt to different collection methods might not be possible. To avoid the risk of needing to change tools, maximize compatibility with any third-party tools that support uploading to S3 buckets. The method introduced in this post to generate time-limited, scoped down credentials can be used with most third-party forensic tools that support uploading to S3 buckets.
  4. Credential vending – Use time-limited tokens, which can be vended on demand through an automated process, eliminating the need for forensic investigators to use the AWS Management Console, understand least privilege, or have any access to the AWS control plane. Forensic investigators can focus on the process of collecting and analyzing evidence.
  5. Process automation – Deploy the process as infrastructure as code (IaC) and automate it through AWS services, reducing the burden on security teams to manually perform runbook steps during an active security incident.

This post starts with an overview of the digital forensic process, provides best practices for using Amazon S3 to store forensic artifacts, details how you can create time-limited, least privilege tokens to provide secure access to upload forensic artifacts to S3 buckets, and introduces a sample architecture that automates the end-to-end process.

The digital forensic process

Organizations need to have practices and resources in place to support a digital forensic investigation environment before an incident occurs. AWS has published several resources, including Forensic investigation environment strategies in the AWS Cloud and AWS prescriptive guidance: Security Reference Architecture, Cyber forensics, to provide best practices for organizing your AWS accounts using AWS Organizations to support forensic clean-room environments. Creating segregated AWS accounts and resources for your security teams is critical to provide your incident responders a location to store and analyze any digital forensic evidence collected during an investigation.

After you’ve established a landing zone for performing digital forensics, you’re ready to collect and process digital forensic evidence. AWS supports the collection of digital forensics through extensive logging of control plane events in AWS CloudTrail, and metrics and application logs that can be stored in Amazon CloudWatch. In addition, AWS core compute services, such as Amazon Elastic Compute Cloud (Amazon EC2), support forensics operations through snapshots of the underlying Amazon Elastic Block Storage (Amazon EBS) volume. An example architecture to demonstrate how to automate the collection of EBS volume snapshots for forensic investigations can be found in How to automate forensic disk collection in AWS.

You might want to use the same AWS infrastructure to collect, examine, analyze, and report on forensic incidents that occur on other resources, such as corporate laptops. You can use existing forensic tooling to perform live response, collecting specific artifacts such as Windows NT File System (NTFS) Master File Table (MFT), logs from Linux machines, volatile memory images, or other artifacts that are specified as part of your organization’s incident response plan. These tools can be provided by third parties or built in-house, and many support uploading to S3 buckets using AWS security credentials.

Using Amazon S3 for forensic artifact collection

Amazon S3 provides the foundational requirements for collecting and storing forensic artifacts. Digital forensics requires highly available, durable, and secure storage of artifacts collected from potentially compromised systems. Amazon S3 is designed for 11 nines of durability and can be configured to provide protection against modification, deletion, and unauthorized access to sensitive forensic artifacts. You can also use S3 to store forensic artifacts of almost any size—from one byte to 5 TB—in an S3 object.

S3 buckets used to store forensic artifacts require custom configuration to provide additional security. You should configure the S3 bucket that you use to store forensic artifacts to enable the following security and governance features:

  1. Encryption in transit. You can require the use of encryption in transit and specify acceptable TLS versions using the aws:SecureTransport and s3:TlsVersion condition keys on the S3 bucket policy.
  2. Encryption at rest using a customer managed key. You can automatically encrypt all objects uploaded to the bucket using a specified customer managed key by specifying a default server-side encryption key in the bucket’s configuration. For this post, we encourage you to use a customer managed key rather than relying upon an AWS managed key, so you can control the associated key policy.
    1. Encryption at rest provides an additional layer of protection, because only entities that have both the permission to read from the bucket and permission to use the AWS Key Management Service (AWS KMS) key for decryption can download the forensic artifact from the S3 bucket.
    2. You need to adjust the example KMS policies in this post if the evidence collection S3 bucket uses the S3 Bucket Key feature.
  3. Audit logs of all S3 data event activity. You can turn on CloudTrail data events for any S3 buckets that contain forensic artifacts to provide a comprehensive audit trail of S3 object-level API activity. This helps provide a chain of custody of any artifacts stored in your forensic buckets.
  4. Fine-grained access control using IAM permissions. You can define the set of entities (both human and machine) that have access to the artifacts in the S3 bucket. This post includes how to create time-limited, least privilege access using IAM permissions for uploading files into an S3 bucket. The permissions are fine-grained enough to scope down access to specific object names or object prefixes in an S3 bucket. Additionally, access to read the artifacts can be controlled through IAM permissions and access to the encryption-at-rest KMS key.
  5. Protections against data modification and deletion. S3 provides features, such as S3 object versioning, to provide assurances that data hasn’t been modified or removed after it’s been collected. This is an additional layer of protection beyond the fine-grained access permissions, so even if an authorized entity attempts to overwrite or delete an object in the S3 bucket, the previous version of the object is still available.
  6. There are additional options that you can configure on the S3 bucket to protect your data against modification and deletion, including S3 Object Lock and multi-factor authentication (MFA) delete.

In addition to the preceding configuration, consider how to organize forensic artifacts in the S3 bucket. This post introduces a folder structure using S3 object prefixes to segregate each forensic artifact collection task into its own S3 object namespace. An example S3 namespace structure for an S3 bucket is shown in Figure 1.
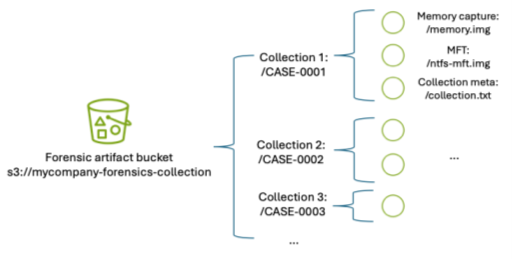
Figure 1 – S3 namespace structure for an S3 forensics artifact bucket using object prefixes

Figure 1: S3 namespace structure for an S3 forensics artifact bucket using object prefixes

By separating each forensic collection task by its own prefix, you can use fine-grained IAM permissions to permit object uploads only into the active collection task. For example, scoped down credentials can be generated to only allow uploads into buckets with the CASE-0001 prefix using an IAM permission as shown in the following code example. Temporary security credentials can be generated using these limited permissions and the key is then used by the forensic acquisition tool to upload the artifacts into the S3 bucket.

{
	"Sid": "UploadToCase0001",
	"Effect": "Allow",
	"Action": [
		"s3:PutObject",
		"s3:AbortMultipartUpload"
	],
"	Resource": "arn:aws:s3:::mycompany-forensics-collection/CASE-0001/*"
}

Manually creating temporary IAM credentials for each forensic collection activity can be error-prone and time-consuming. Therefore, this post demonstrates how to use AWS tooling to automate the process of generating time-limited, scoped-down credentials.

Adapt existing forensic tools for AWS best security practices

Existing forensic tools typically use IAM access keys to perform S3 operations. Using a static IAM user secret access key isn’t a best practice. Even if the static key is associated with an IAM user that has been scoped down to only have access to the forensic collection S3 bucket as described previously, that means anyone with access to that key can potentially upload objects into that bucket. Therefore, the best practice is to create a time-limited temporary security credential unique to each collection activity, scoped down to only allow uploading files to a specific prefix in the target S3 bucket.

The examples in this post use the following resource names. Because these names will change based on your deployment, substitute your resource names in place of the names in the example code.

  1. The evidence S3 bucket is named mycompany-forensics-collection
  2. The forensics AWS account number is 112233445566. For the purposes of this example, all resources will live within this account.
  3. The customer managed key used to encrypt the forensic artifacts at rest is ForensicsEvidenceKey
  4. The IAM role that incident responders will assume when signing in to their AWS account is ForensicsUserRole
  5. The IAM role that incident responders will use for generating S3 file upload temporary credentials is ForensicsUploadRole
  6. The example uses the us-east-1 AWS Region

The following steps show you how to configure the IAM policies associated with the customer managed key ForensicsEvidenceKey and the IAM role ForensicsUploadRole.
Before you begin, create the evidence S3 bucket configured as described in Using S3 for artifact collection and a customer managed key to encrypt the forensic artifacts at rest. Configure the evidence S3 bucket to use the KMS key by opening the S3 bucket’s properties tab in the Amazon S3 console and setting the new KMS key as the default encryption key for the bucket.

Next, create an IAM role that incident responders will assume through the AWS STS AssumeRole API to generate the temporary credentials. This role will define the maximum set of permissions allowed to upload artifacts to your evidence S3 bucket. This role, ForensicsUploadRole, created using the following example code, defines the maximum allowable permissions: the ability to upload objects into the evidence S3 bucket and to use the KMS key to encrypt those uploads. The effective permissions available to the forensic tool will be scoped down even further to the specific object prefix when the AWS STS temporary security credential is generated.

Note that the policy allows the forensics upload role Decrypt permission in addition to Encrypt; this is required when uploading files larger than 5 GB using the multi-part S3 file upload feature.

{
	"Version": "2012-10-17",
	"Statement": [
			{
				"Sid": "BasePermissionsForS3Upload",
				"Effect": "Allow",
				"Action": [
					"s3:PutObject",
					"s3:AbortMultipartUpload"
				],
				"Resource": "arn:aws:s3:::mycompany-forensics-collection/*"
		},
		{
			"Sid": "KeyAccessToS3Upload",
			"Effect": "Allow",
			"Action": [
				"kms:GenerateDataKey",
				"kms:Encrypt",
				"kms:Decrypt"
			],
			"Resource": "arn:aws:kms:us-east-1:112233445566:alias/ForensicsEvidenceKey",
			"Condition": {
				"StringLike": {
					"kms:EncryptionContext:aws:s3:arn": "arn:aws:s3:::mycompany-forensics-collection/*"
				}
			}
		}
	]
}

Next, you need to provide an ability to assume this role and generate AWS STS tokens using the role’s permissions. This is accomplished by creating a trust relationship associated with the IAM role you just created. The trust relationship shown in the following code sample describes which AWS principals are allowed to assume the role—in this case, you will allow any user who has federated into the ForensicsUserRole IAM role to be able to generate AWS STS tokens for forensic artifact collection.

{
	"Version": "2012-10-17",
	"Statement": [
		{
			"Sid": "Statement1",
			"Effect": "Allow",
			"Principal": {
				"AWS": "arn:aws:iam::112233445566:role/ForensicsUserRole"
			},
			"Action": "sts:AssumeRole"
		}
	]
}

After the role is established and access to the encryption key is granted, you can use the AWS STS AssumeRole API to create temporary credentials using this role. You can call this API using the AWS Command Line Interface (AWS CLI) or programmatically from a script. To scope down the token’s access to only provide permission to upload to the specific evidence object prefix, you must include a session policy as part of your AssumeRole API request to AWS STS. The following is an example session policy to restrict access to only upload objects into the CASE-0001 prefix.

[
	{
		"Effect": "Allow",
		"Action": [
			"s3:PutObject", 
			"s3:AbortMultipartUpload"
		],
		"Resource": "arn:aws:s3:::mycompany-forensics-collection/CASE-0001/*"
	},
	{
		"Effect": "Allow",
		"Action": [
			"kms:GenerateDataKey", 
			"kms:Encrypt", 
			"kms:Decrypt"
		],
		"Resource": "*",
		"Condition": {
			"StringLike": {
				"kms:EncryptionContext:aws:s3:arn": "arn:aws:s3:::mycompany-forensics-collection/CASE-0001/*"
			}
		}
	}
]

The effective permissions available to the session role will be the intersection of permissions available in the role policy (ForensicsUploadRole), the resource policy (in this case, mandating TLS-encrypted connections to the bucket), and the session policy that’s created on demand for every forensic collection (only allowing access to upload objects into the CASE-0001 prefix, as shown in the preceding example). Pictorially, this looks like the Venn diagram shown in Figure 2.
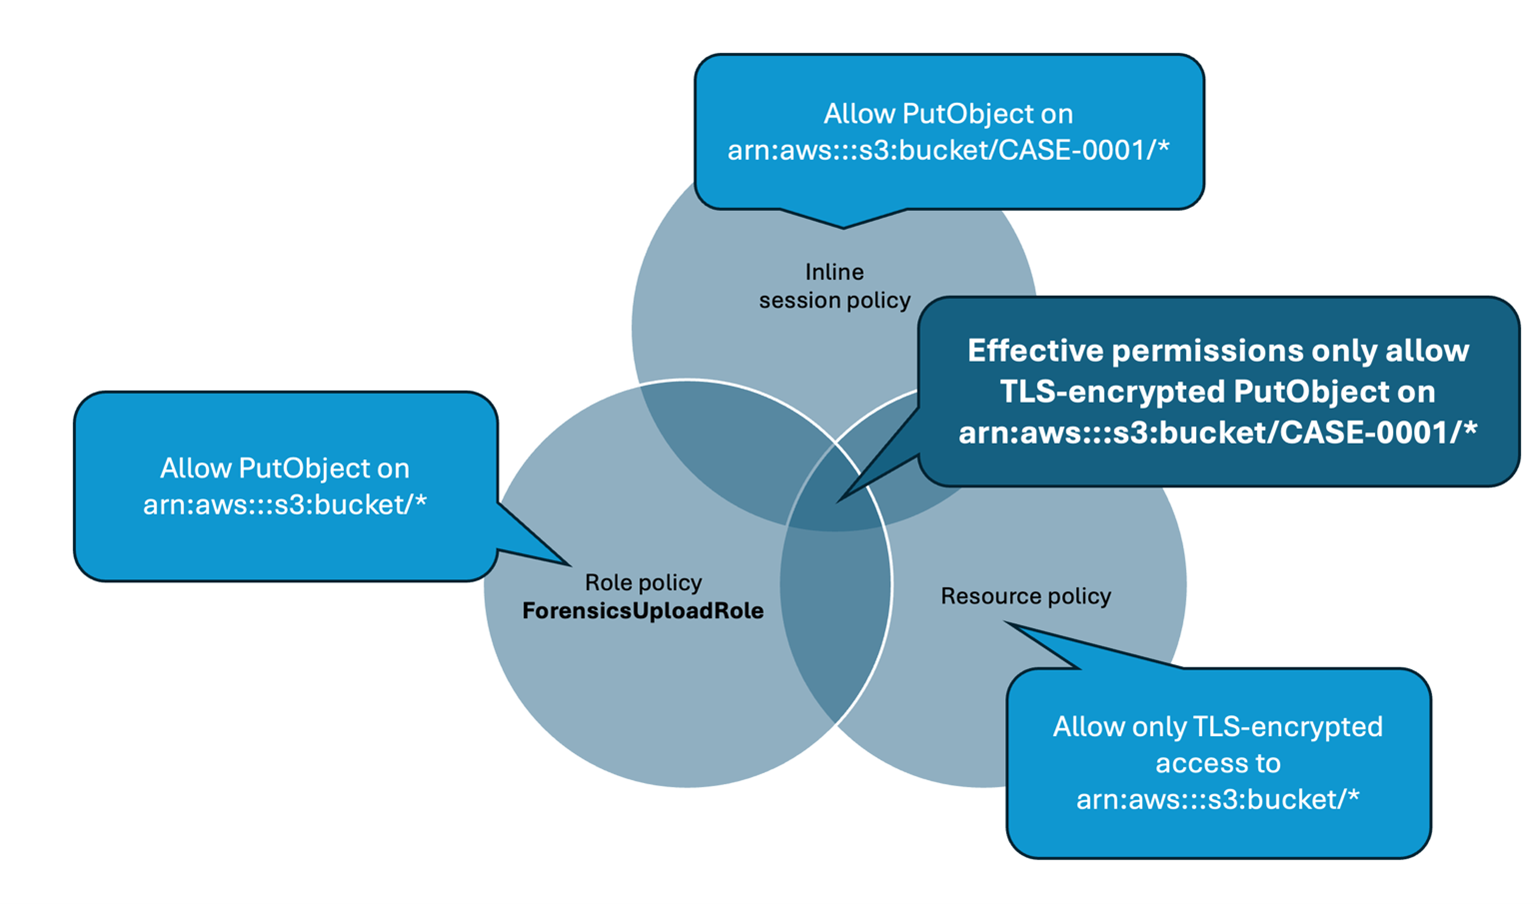
Figure 2 – Intersection of IAM policies determine the effective permissions for the restricted forensic session role.

Figure 2: Intersection of IAM policies determine the effective permissions for the restricted forensic session role.

Test the temporary credentials

Now that the bucket has been created and the AWS KMS key and roles configured, you can use AWS STS to create a temporary security credential for a collection on CASE-0001. You can use the AWS CLI to do this manually or you can write a script to automate this process using the AWS API. The IAM access key, secret access key, and session token returned by this call can then be used by any tool that can use AWS access keys to upload files into the specified S3 bucket.

The following example shows an AWS CLI call to AssumeRole using the example ForensicsUploadRole and a case named CASE-0001. The --duration-seconds parameter defines the period, in seconds, that the temporary credentials are valid; the default of 3600 seconds will provide temporary credentials that are valid for one hour.

$ aws sts assume-role \
	--role-arn arn:aws:iam::112233445566:role/ForensicsUploadRole \
	--role-session-name CASE-0001 \
	--duration-seconds 3600 \
	--policy '{"Version": "2012-10-17", "Statement": [{"Effect": "Allow", "Action": ["s3:PutObject", "s3:AbortMultipartUpload"], "Resource": "arn:aws:s3:::mycompany-forensics-collection/CASE-0001/*"}, {"Sid": "BasePermissionsForS3Upload", "Effect": "Allow", "Action": ["kms:GenerateDataKey", "kms:Encrypt", "kms:Decrypt"], "Resource": "*"}]}'

{
	"Credentials": {
		"AccessKeyId": "ASIAXXXX",
		"SecretAccessKey": "XXXX",
		"SessionToken": "XXXX",
		"Expiration": "2025-04-10T17:16:13+00:00"
	},
	"AssumedRoleUser": {
		"AssumedRoleId": "AROXXXX:CASE-0001",
		"Arn": "arn:aws:sts::112233445566:assumed-role/ForensicsUploadRole/CASE-0001"
	},
	"PackedPolicySize": 39
}

Now that you have obtained temporary credentials from AWS STS, you can use those credentials to upload a file into Amazon S3:

$ AWS_ACCESS_KEY_ID=ASIAXXXX \
	AWS_SECRET_ACCESS_KEY=XXXX \
	AWS_SESSION_TOKEN=XXXX \
	aws s3 cp evidence.zip s3://mycompany-forensics-collection/CASE-0001/evidence.zip

upload: evidence.zip to s3://mycompany-forensics-collection/CASE-0001/evidence.zip

You can also verify that you can’t use those credentials to upload a file into any other object prefixes or S3 buckets. For example, if you change CASE-0001 to CASE-0004 in the Amazon S3 upload command, you will receive an AccessDenied error because you’re trying to upload an object outside of the allowed key prefix.

$ AWS_ACCESS_KEY_ID=ASIAXXXX \
	AWS_SECRET_ACCESS_KEY=XXXX \
	AWS_SESSION_TOKEN=XXXX \
	aws s3 cp evidence.zip s3://mycompany-forensics-collection/CASE-0004/evidence.zip

upload failed: evidence.zip to s3://mycompany-forensics-collection/cases/CASE-0004/evidence.zip
An error occurred (AccessDenied) when calling the PutObject operation: User: arn:aws:sts::112233445566:assumed-role/ForensicsUploadRole/CASE-0001 is not authorized to perform: s3:PutObject on resource: "arn:aws:s3:::mycompany-forensics-collection/CASE-0004/evidence.zip" because no session policy allows the s3:PutObject action

Additionally, if you wait more than the lifetime of the token (1 hour in this case), attempting to upload a file into the bucket will fail, because the token will no longer be valid:

$ AWS_ACCESS_KEY_ID=ASIAXXXX \
	AWS_SECRET_ACCESS_KEY=XXXX \
	AWS_SESSION_TOKEN=XXXX \
	aws s3 cp evidence.zip s3://mycompany-forensics-collection/CASE-0001/evidence.zip

upload failed: evidence.zip to s3://mycompany-forensics-collection/CASE-0001/evidence.zip

An error occurred (ExpiredToken) when calling the PutObject operation: The provided token has expired.

Create an automated process to vend temporary credentials on demand

After you’ve verified the security benefits of creating temporary credentials for S3 uploads and validated that the credentials work with your forensic software of choice, you can now use them as part of an automated process.

A sample automated architecture is shown in Figure 3.
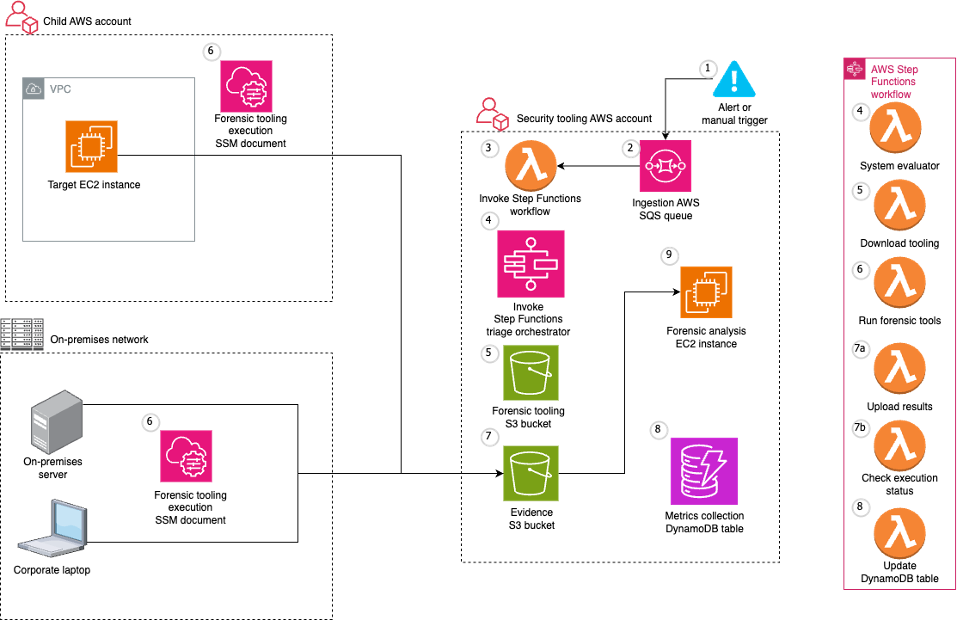
Figure 3: Architecture to automate S3 credential vending and forensic artifact collection.

Figure 3: Architecture to automate S3 credential vending and forensic artifact collection.

The workflow depicted in Figure 3 includes the following steps:

  1. The workflow is triggered by an alert from a detection source or a manual trigger from an incident responder.
  2. The workflow input is added to an Amazon Simple Queue Service (Amazon SQS) queue.
  3. The Amazon SQS queue invokes an AWS Lambda function which in turn executes a Step Functions state machine to orchestrate the workflow.
  4. First, the Step Functions workflow determines whether the target system is managed by AWS Systems Manager.
    1. If the target system isn’t managed by Systems Manager, an error is noted, and the execution is abandoned.
    2. If the target system is managed by Systems Manager, the Step Functions workflow determines the operating system (OS) of the target system and proceeds with the flow of execution.
  5. The workflow then continues by executing the Systems Manager documents that implement the forensic collection process:
    1. Downloads tooling:
      1. Generates dynamically scoped IAM temporary credentials that provide access to download the OS-specific tooling to be executed on the target system from the tooling S3 bucket. These credentials are tightly scoped to only allow downloads from the S3 prefix that corresponds to the tooling for the target system’s OS.
      2. Executes a Systems Manager command on the target system that uses the credentials generated from the previous step to download the OS tooling on the target system.
    2. Runs forensic tools:
      • Executes a Systems Manager command on the target system to execute the OS tooling on the target system.
  6. The Systems Manager commands run on the target system, which in this case is an EC2 instance.
  7. Results are uploaded to the evidence S3 bucket:
    1. Generates dynamically scoped IAM temporary credentials (as described previously) that provide access to upload the output of the previously executed tooling to the evidence S3 bucket. These credentials are tightly scoped to only allow uploads to a particular S3 prefix corresponding to the alert prefix.
    2. Executes a Systems Manager command on the target system to upload the output of the previously executed tooling to the evidence S3 bucket. After the upload is complete, it cleans up both the output and the evidence tooling from the target system.
    3. The evidence S3 bucket is tightly locked down to a subset of identities within the AWS security account. Access attempts from identities that aren’t allow listed trigger an Amazon EventBridge rule to alert the security team through an Amazon Simple Notification Service (Amazon SNS) topic.
  8. When the workflow is complete, related details and metrics are recorded in an Amazon DynamoDB table.
  9. The forensic analysis can be performed on a separate EC2 instance that has access to read from the evidence S3 bucket.

Deploying the example solution

You can use the AWS Cloud Development Kit (AWS CDK) repository to implement the architecture shown in Figure 3.

The AWS CDK solution is split into three stacks:

  1. SecurityStack: This stack contains the basic forensic artifact workflow orchestration infrastructure described in this post, including the Step Functions workflow, Lambda functions, AWS SQS queues, IAM roles, and S3 buckets.
  2. AlertStack: This stack contains the EventBridge workflow to notify administrators of anomalous activity in the evidence S3 bucket.
  3. CustomerStack: This stack contains the SSM documents that are executed for the forensic artifact workflow and an IAM role assumed by the SecurityStack when the workflow is invoked. It’s deployed into each child AWS account containing EC2 instances from which the security account is authorized to collect forensic artifacts.

Configuration

Before deploying the solution, there are several variables in the config.ts file that must be modified for the environment:

  1. SECURITY_ACCOUNT: Security Tooling AWS account ID.
  2. CUSTOMER_ACCOUNTS: Target AWS account IDs (the Child AWS account in the architecture diagram).
  3. ALERT_EMAIL_RECIPIENTS: List of email addresses that receive alerts when there is unexpected access to the evidence S3 bucket.
  4. ALLOW_LISTED_ROLE_NAMES: Roles allowed to access the evidence S3 bucket. Any other identities accessing the evidence S3 bucket will result in an alarm.

Deployment

After you’ve updated the config.ts file to reflect the account numbers, email recipients, and role names, the stacks can be deployed into your AWS infrastructure.

  1. Set Up AWS credentials using the AWS CLI:
    aws configure
  2. Install dependencies and configure constants:
    1. Clone the repository.
    2. Navigate to the project directory.
    3. Install project dependencies:
      npm install
    4. Configure constants in constants/config.ts with the required information:
      export const SECURITY_ACCOUNT = "123456789012"; // Your security tooling account ID 
      export const CUSTOMER_ACCOUNTS = ["234567890123", "345678901234"]; // Target account IDs 
      export const ALLOW_LISTED_ROLE_NAMES = ["SecurityAnalystRole"];// Roles allowed to access evidence S3 bucket 
      export const ALERT_EMAIL_RECIPIENTS = ["[email protected]"];// Email addresses for alerts

  3. Bootstrap AWS CDK in your accounts (if it hasn’t been done already):
    1. Example: cdk bootstrap aws://456789012345/us-east-1 (example security AWS account).
    2. Then bootstrap if necessary in any target AWS accounts.
  4. Deploy the AWS CDK Stacks:
    1. Synthesize the CloudFormation template:
      cdk synth
    2. Deploy the security and alert stacks in your security account:
      cdk deploy SecurityStack AlertStack
    3. Deploy the customer stacks in your workload accounts:
      cdk deploy CustomerStack-ACCOUNT_ID
  5. Set up your email alerts:
    1. After the AlertStack is deployed, it will email all addresses listed in ALERT_EMAIL_RECIPIENTS. Choose the embedded link to accept the AWS SNS topic in each of those accounts.

Testing

With deployment complete, it’s time to test the solution.

  1. Trigger an analysis
    1. Make sure you have a Linux EC2 instance running in one of your customer accounts and in the AWS Region where you deployed the preceding customer stack.
    2. Because this example uses Systems Manager to orchestrate the collection script, make sure that the EC2 instance is visible in Systems Manager either by checking the Systems Manager console, or by using the AWS CLI:
      1. Console: In the AWS Systems Manager console, choose Managed instances in the left navigation pane and verify your instance appears in the list. For more information, see Managed Instances in the AWS Systems Manager User Guide.
      2. AWS CLI: Run the following command to verify the instance is managed:
        aws ssm describe-instance-information --filters “Key=InstanceIds,Values=<instance-id>
        If the command returns instance information with PingStatus: Online, the instance is properly connected to Systems Manager.
    3. Post a message in your security account to the Amazon SQS queue to start the Step Functions workflow. Note that the values in angle brackets (for example <accountID>) are placeholders that you must update with relevant AWS account ID, tracking ticket ID, AWS Region, and EC2 instance ID values:
      aws sqs send-message --queue-url --message-body ‘{ “account”: “”, “ticket_id”: “”, “region”: “>”, “instance_id”: “” }’
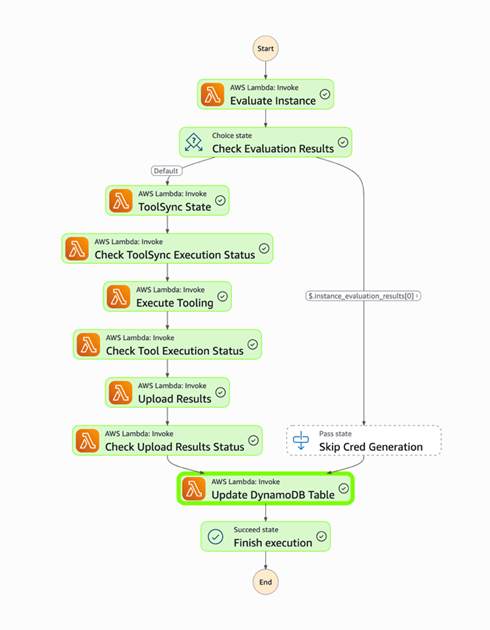
  2. Go to the Step Functions console to view the successful execution of the workflow:
    Figure 4 – Workflow as shown in the Step Functions console

    Figure 4: Workflow as shown in the Step Functions console

  3. View the DynamoDB table to see the metadata for the results.
  4. Check the evidence S3 bucket to see the uploaded files from the forensic collection.
Conclusion

Collecting forensic artifacts securely is a critical component of any digital forensics investigation. This post demonstrated how to implement least privilege access controls and time-limited credentials for forensic evidence collection workflows that use Amazon S3 for artifact storage. By combining IAM session policies with AWS STS temporary credentials, you can provide forensic tools with secure, scoped-down access to upload artifacts without exposing long-lived credentials or granting overly permissive access.

The architecture presented in this post automates the process of generating temporary credentials, collecting forensic artifacts from both AWS and non-AWS resources, and securely storing them in S3 buckets with appropriate encryption, access controls, and audit logging. With this approach, your security teams can focus on analyzing evidence instead of managing credentials and permissions during active security incidents.To get started with this solution, deploy the example AWS CDK stacks provided in the collect forensic artifacts repository and customize them for your organization’s forensic investigation requirements. For more information about related AWS forensic investigation architectures, review the Automated Forensics Orchestrator for EC2 and How to build forensic kernel modules for Linux EC2 instances resources.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.

Jason Garman

Jason Garman

Jason is a principal security specialist solutions architect at AWS. He has 30 years of cybersecurity experience including incident response, reverse engineering, identity, and data protection. At AWS, he helps large organizations adopt the latest cloud and AI technologies while maintaining a high bar for data governance, security, and safety.

Vaishnav Murthy

Vaishnav Murthy

Vaishnav is a Senior Security Engineer with AWS CloudResponse. He has an extensive background in incident response and security automation and enjoys building automated solutions that help AWS customers investigate and respond to security incidents at scale.

Evolving Cloudflare’s Threat Intelligence Platform: actionable, scalable, and ETL-less

Post Syndicated from Blake Darché original https://blog.cloudflare.com/cloudflare-threat-intelligence-platform/

For years, the cybersecurity industry has suffered from a “data gravity” problem. Security teams are buried under billions of rows of telemetry, yet they remain starved for actionable insights. 

A Threat Intelligence Platform (TIP) is a centralized security system that collects, aggregates, and organizes data about known and emerging cyber threats. It serves as the vital connective tissue between raw telemetry and active defense.

The underlying architecture of Cloudflare’s Threat Intelligence Platform sets it apart from other solutions. We have evolved our Threat Intelligence Platform to eliminate the need for complex ETL (Extract, Transform, Load) pipelines by using a sharded, SQLite-backed architecture. By running GraphQL directly on the edge, security teams can now visualize and automate threat response in real time. Instead of one massive database, we distribute Threat Events across thousands of logical shards — meaning sub-second query latency, even when aggregating millions of events across global datasets.

By unifying our global telemetry with the manual investigations performed by our analysts, our intelligence platform creates a single source of truth that allows security teams to move from observing a threat to preemptively blocking it across the Cloudflare network. We believe your intelligence platform shouldn’t just tell you that something is “bad”; it should tell you why it’s happening, who is behind it, and automatically prevent it from happening again. 

In this post, we’ll explore some of the features that make the Cloudforce One experience powerful and effective.

Why are we launching a Threat Intelligence Platform?

When we announced the Cloudforce One team in 2022, we quickly realized that tracking adversary infrastructure required tools that didn’t yet exist. So we built our own.

What began as an internal project has evolved into a cloud-first, agentic-capable Threat Intelligence Platform (TIP) designed for our users. We have moved from conceptualizing “observable” events across various datasets to building a platform that maps the entire lifecycle of a threat. Today, the Cloudflare TIP allows you to correlate actors to malware, link cases to indicators, and store everything in one unified ecosystem.

We are moving beyond simple data access to provide a fully integrated, visual, and automated command center for your SOC. Our motivation behind building this TIP stems from the core tenets of effective threat intelligence: relevance, accuracy, and actionability. We needed a highly extensible system that can integrate multiple datasets, support multi-tenancy, enable group-based and tenant-to-tenant sharing, and scale efficiently on the edge. 

By using Cloudflare Workers, we’ve built a next-generation developer stack that ensures rapid innovation. We can now synthesize millions of threat events into real-time graphs and diagrams and instantly answer the critical questions: What happened? And what does it mean? 

Because our GraphQL endpoint is built in the same Worker that is driving the Threat Events platform, your data is always live and there are no delays between ingestion and availability. Whether you are applying complex analysis or drilling down into a specific event, the platform responds instantly. As Workers runtime evolves, our TIP inherits these optimizations automatically. For example, Smart Placement ensures our query-handling Workers are physically located near the Durable Objects they are fanning out to, minimizing tail latency. And the ability to use larger CPU limits and Hyperdrive allows us to maintain higher performance connection pooling directly at the edge, rather than backhauling the logic to a single datacenter.

Beyond the SIEM: historical context and intelligence enrichment

While a SIEM (Security Information and Event Management) is designed for real-time log aggregation and immediate alerting, it often lacks the specialized schema and long-term retention needed for deep adversary tracking. Our TIP fills this gap by acting as a dedicated intelligence layer that enriches raw logs with historical actor patterns. The goal of our platform isn’t to replace a SIEM, but to complement it. Our TIP provides the long-term, structured storage for Threat Events — retained and indexed at the edge — needed to bridge the gap between technical telemetry and executive insight.

The Cloudflare Managed Defense and Threat Intelligence Platform are designed to operate in a symbiotic loop, creating a powerful force multiplier for threat detection and response. By integrating the TIP directly with the SOC, analysts gain immediate, rich context for any alert or event. Instead of just seeing an anomalous IP address or a suspicious file hash, the SOC team can instantly see its history, its association with known threat actors, its role in broader campaigns, and its risk score as determined by the TIP’s analytics. This immediate context eliminates time-consuming manual research and enables faster, more accurate decision-making.

Conversely, as the intel analyst team investigates incidents and hunts for new threats, their findings become a crucial source of new intelligence. 

Newly discovered indicators of compromise (IOCs) are fed back into the TIP, enriching the platform for all users and enhancing its automated defenses. This continuous feedback loop ensures the intelligence is always current and grounded in real-world observations, providing unparalleled visibility into the threat landscape and allowing security teams to shift from a reactive to a proactive defense posture.

An architecture that eliminates bottlenecks

To ensure every piece of Cloudforce One telemetry is actionable, we had to solve a fundamental storage problem: how do you provide low-latency, complex queries over billions of events without the overhead of a traditional centralized database?

We chose a sharded architecture built on SQLite backed Durable Objects. By distributing Threat Events across this high-cardinality fleet of storage units, we ensure that no single database becomes a point of contention during high-volume ingestion. Each shard is a Durable Object, providing a consistent, transactional interface to its own private SQLite database.

This architecture allows us to use the full Cloudflare developer stack. We use Cloudflare Queues to ingest and distribute incoming telemetry asynchronously, ensuring that high-volume attack spikes don’t saturate our write throughput. Once ingested, data is stored in R2 for long-term retention, while the “hot” index remains in the Durable Object’s SQLite storage for instant retrieval.

Parallel execution at the edge

The real power of this approach is visible during a search. When a user queries our GraphQL endpoint — which also runs in a Worker — the platform doesn’t query a single table. Instead, it fans out the request to multiple Durable Objects in parallel. Because Durable Objects are distributed across our global network, we can aggregate results with minimal latency. After we verify the user’s permissions and eliminate the shards that would not contain our events (by date), here is a simplified look at how the Worker handles a multi-shard fan-out:

// A conceptual look at fanning out a query to multiple shards
async function fetchFromShards(shards, query) {
  const promises = shards.map(shardId => {
    const stub = TELEMETRY_DO.get(shardId);
    return stub.querySQLite(query); // Calling the DO's storage method
  });

  // Parallel execution across the Cloudflare network
  const results = await Promise.all(promises);
  return results.flat();
}

This parallelism ensures a fluid experience whether you are auditing a single dataset for a year of history or synthesizing a month of activity across every dataset in your account. By moving the compute — the SQL execution — to where the data lives, we eliminate the bottleneck of a single, monolithic database.

Visualize the Adversary with dynamic graphs and diagrams

Numbers on a spreadsheet don’t tell stories; patterns do. We’ve introduced dynamic visualizations to help you “see” the threat landscape.

  • Sankey Diagrams to trace the flow of attacks from origin to target, identifying which regions are being hit hardest and where the infrastructure resides.

  • Industry and dataset distribution of attacks, for users to instantly pivot your view to see if a specific campaign is targeting your sector (e.g., Finance or Retail) or if it’s a broad-spectrum commodity attack.

Correlating telemetry through attribute mapping

A single indicator, such as an IP address, provides limited utility without historical and relational context. We have structured our Threat Insights to act as a pivot point, allowing you to correlate disparate threat events across multiple datasets into a single, cohesive campaign or exploit.

Instead of manual cross-referencing, the platform automatically maps our internal actor nomenclature to recognized industry aliases — such as linking our internal tracking to “Fancy Bear” or “APT28.” This ensures that your local environment’s telemetry is instantly interoperable with broader global research and threat intelligence feeds.

Search, filters, and alerts

Saved configurations and real-time notifications help you get notified the second our telemetry matches your custom filters, allowing you to react at the speed of the edge. Effective threat hunting requires the ability to filter global telemetry by specific technical attributes. The platform supports high-cardinality searches across our entire dataset — including IP addresses, file hashes, domains, and JA3 fingerprints — with results typically returned in seconds.

To move beyond manual searching, you can persist these query parameters as saved configurations. These configurations act as triggers for our real-time notification engine; when new incoming telemetry matches your defined filters, the platform pushes an alert to your configured endpoints. This transition from pull-based searching to push-based alerting ensures that your security stack can respond to matches as soon as they are ingested by our global network.


Automated rules and STIX2 Exports

Intelligence is only “actionable” if it results in a reduced attack surface. We’ve built the TIP to handle the translation between raw telemetry and security enforcement automatically.

For organizations using third-party or in-house SIEM or SOAR platforms, interoperability is a requirement. However, mapping disparate internal data schemas to the STIX2 (Structured Threat Information eXpression) standard is traditionally a high-latency ETL task. We’ve moved this translation to the edge. 

When a user requests a STIX2 export, a Worker dynamically maps our internal SQLite records to the STIX2 JSON schema. This means we are first converting raw IP addresses, file hashes, and domain names into standardized STIX cyber observables. Then we define relationship objects using our platform’s internal mapping to link indicator objects to threat-actor or malware objects, preserving the context of the investigation. Finally, we automatically manage the modified and created timestamps in UTC to ensure your downstream tools can track the evolution of the threat.

Instant Protection via the Firewall API

Beyond exports, the platform allows you to close the loop between discovery and defense. When you identify a malicious pattern in a Sankey diagram or a specific Actor campaign, you can generate a security rule with one click.

Under the hood, the TIP interacts directly with the Cloudflare Firewall Rules API. It takes the filtered attributes of your investigation (e.g., a specific JA3 fingerprint combined with a list of known malicious ASNs) and compiles them into a wire-protocol rule that is deployed across our global network in seconds.

Human-in-the-loop intelligence

While automation handles the bulk of telemetry, the most complex threats require human intuition. We’ve integrated a Requests for Information (RFI) Portal directly into the platform, allowing users to task Cloudforce One analysts with deep-dive investigations.

From a technical perspective, the RFI system isn’t just a ticketing portal; it’s a data-enrichment pipeline. When a subscriber uses a number of “tokens” to initiate a request, the workflow triggers a series of events:

  • The RFI Worker pulls the specific Threat Event IDs related to the query from the sharded SQLite storage, packaging the relevant telemetry for the analyst

  • Cloudforce One analysts use an internal version of the TIP to perform reverse engineering or pivot across global datasets

  • Once the investigation is complete, the findings (new IOCs, actor attributions, or campaign notes) are written back into our global intelligence feed

This ensures that the “human” insight doesn’t just sit in a PDF report. Instead, the resulting metadata is pushed back to the edge as a threat event where relevant, where it can be used by the WAF or Firewall rules you’ve already configured. We’ve moved from a static “report” model to a dynamic “intel-as-code” model, where human analysis directly improves the platform’s automated detection logic in real time.


From data management to active hunting

The shift from managing ETL pipelines to active threat hunting isn’t just about a new interface but about where the compute happens. By moving the storage, aggregation, and visualization layers to the Cloudflare global network, we’ve removed the “data gravity” that typically slows down a SOC. Defenders no longer need to wait for logs to sync to a central repository before they can ask, “Is this IP related to a known campaign?” The answer is now available at the edge, in the same environment where the traffic is being filtered.

To ensure this intelligence is accessible regardless of your team’s size or specific requirements, we’ve structured our Cloudforce One access into three functional levels:

  • Cloudforce One Essentials allows customers to access the default datasets in threat events, search for indicators, and conduct threat hunting investigations.

  • Cloudforce One Advantage allows customers to access our Threat Intelligence Analyst custom insights via requests for information.

  • Cloudforce One Elite, the complete package, includes brand protection, a high number of requests for information, and access to all threat events datasets.

The Internet moves fast, and the infrastructure used by adversaries moves even faster. By centralizing your telemetry and your response logic in one integrated platform, you can stop building pipelines and start defending your network.

 [Threat Landscape Report 2026] [Explore the Threat Intelligence Platform] | [Contact Sales for a Demo]

Introducing REACT: Why We Built an Elite Incident Response Team

Post Syndicated from Chris O’Rourke original https://blog.cloudflare.com/introducing-react-why-we-built-an-elite-incident-response-team/

Cloudforce One’s mission is to help defend the Internet. In Q2’25 alone, Cloudflare stopped an average of 190 billion cyber threats every single day. But real-world customer experiences showed us that stopping attacks at the edge isn’t always enough. We saw ransomware disrupt financial operations, data breaches cripple real estate firms, and misconfigurations cause major data losses.

In each case, the real damage occurred inside networks.

These internal breaches uncovered another problem: customers had to hand off incidents to separate internal teams for investigation and remediation. Those handoffs created delays and fractured the response. The result was a gap that attackers could exploit. Critical context collected at the edge didn’t reach the teams managing cleanup, and valuable time was lost. Closing this gap has become essential, and we recognized the need to take responsibility for providing customers with a more unified defense.

Today, Cloudforce One is launching a new suite of incident response and security services to help organizations prepare for and respond to breaches.

These services are delivered by Cloudforce One REACT (Respond, Evaluate, Assess, Consult Team), a group of seasoned responders and security veterans who investigate threats, hunt adversaries, and work closely with executive leadership to guide response and decision-making.

Customers already trust Cloudforce One to provide industry-leading threat intelligence, proactively identifying and neutralizing the most sophisticated threats. REACT extends that partnership, bringing our expertise directly to customer environments to stop threats wherever they occur. In this post, we’ll introduce REACT, explain how it works, detail the top threats our team has observed, and show you how to engage our experts directly for support.

Our goal is simple: to provide an end-to-end security partnership. We want to eliminate the painful gap between defense and recovery. Now, customers can get everything from proactive preparation to decisive incident response and full recovery—all from the partner you already trust to protect your infrastructure.

It’s time to move beyond fragmented responses and into one unified, powerful defense.

How REACT works

REACT services consist of two main components: Security advisory services to prepare for incidents and incident response for emergency situations.


A breakdown of the Cloudforce One incident readiness and response service offerings.

Advisory services are designed to assess and improve an organization’s security posture and readiness. These include proactive threat hunting, backed by Cloudflare’s real-time global threat intelligence, to find existing compromises, tabletop exercises to test response plans against simulated attacks, and both incident readiness and maturity assessments to identify and address systemic weaknesses.

The Incident Response component is initiated during an active security crisis. The team specializes in handling a range of complex threats, including APT and nation-state activity, ransomware, insider threats, and business email compromise. The response is also informed by Cloudflare’s threat intelligence and, as a network-native service, allows responders to deploy mitigation measures directly at the Cloudflare edge for faster containment.

For organizations requiring guaranteed availability, incident response retainers are offered. These retainers provide priority response, the development of tailored playbooks, and ongoing advisory support.

Cloudflare’s REACT services are vendor-agnostic in their scope. We are making REACT available to both existing Cloudflare customers and non-customers, regardless of their current technology stack, and regardless of whether their environment is on-premise, public cloud, or hybrid.

What makes Cloudflare’s approach different?

Our new service provides significant advantages over traditional incident response, where engagement and data sharing occur over separate, out-of-band channels. The integration of the service into the platform enables a more efficient and effective response to threats.

The core differentiators of this approach are:

  • Unmatched threat visibility. With roughly 20% of the web sitting behind Cloudflare’s network, Cloudforce One has unique visibility into emerging attacks as they unfold globally. This lets REACT accelerate their investigations and quickly correlate incident details with emerging attack vectors and known adversary tactics.

  • Network-native mitigation. The service is designed for network-native response. This allows the team, with customer authorization, to deploy mitigations directly at the Cloudflare edge, such as a WAF rule or Secure Web Gateway policy. This capability reduces the time between threat identification and containment. All response actions are tracked within the dashboard for full visibility.

  • Service delivery by proven experts. Cloudforce One is composed of seasoned threat researchers, consultants, and incident responders. The team has a documented history of managing complex security incidents, including nation-state activity and sophisticated financial fraud.

  • Vendor-agnostic scope. While managed through the Cloudflare dashboard, the scope of the response is vendor-agnostic. The team is equipped to conduct investigations and coordinate remediation across diverse customer environments, including on-premise, public cloud, and hybrid infrastructures.

Key Threats Seen During Engagements So Far

Analysis of security engagements by the REACT team over the last six months reveals three prevalent and high-impact trends. The data indicates that automated defenses, while critical, must be supplemented by specialized incident response capabilities to effectively counter these specific threats.

High-impact insider threats 

The REACT team has seen a significant number of incidents driven by insiders who use trusted access to bypass typical security controls. These threats are difficult to detect as they often combine technical actions with non-technical motivations. Recent scenarios observed are:

  • Disgruntled or current employees using their specialized, trusted access to execute targeted, destructive attacks.

  • Financially motivated insiders who are compensated by external actors to exfiltrate data or compromise internal systems.

  • State sponsored operatives gain trusted, privileged access via fraudulent remote work roles to exfiltrate data, conduct espionage, and steal funds for illicit regime financing.

Ransomware

The REACT team has observed that ransomware continues to be a primary driver of high-severity incidents, posing an existential threat to nearly every sector. Common themes observed include:

  • Disruption of core operations in the financial sector via hostage-taking of critical systems. 

  • Paralysis of business functions and compromise of client data in the real estate industry, leading to significant downtime and regulatory scrutiny.

  • Broad impact across all industry verticals. 

Stopping these attacks demands not only robust defenses but also a well-rehearsed recovery plan that cuts time-to-restoration to hours, not weeks.

Application security and supply chain breaches

The REACT team has also seen a significant increase in incidents originating at the application layer. These threats typically manifest in two primary areas: vulnerabilities within an organization’s own custom-developed  (‘vibe coded’) applications, and security failures originating from their third-party supply chain:

  • Vibe coding: The practice of providing natural language prompts to AI models to generate code can produce critical vulnerabilities which can be exploited by threat actors using techniques like remote code execution (RCE), memory corruption, and SQL injection.

  • SaaS supply chain risk: A compromise at a critical third-party vendor that exposes sensitive data, such as when attackers used a stolen Salesloft OAuth token to exfiltrate customer support cases from their clients’ Salesforce instances.

Integrated directly into your Cloudflare dashboard

Starting today, Cloudflare Enterprise customers will find a new “Incident Response Services” tab in the Threat intelligence navigation page in the Cloudflare dashboard. This dashboard integration ensures that critical security information and the ability to engage our incident response team are always at your fingertips, streamlining the process of getting expert help when it matters most.


Screenshot of the Cloudforce One Incident Response Services page in the Cloudflare dashboard

Retainer customers will benefit from a dedicated Under Attack page, which allows customers to contact Cloudforce One team during an active incident. In the event of an active incident, a simple “Request Help” button in our “Under Attack” page will immediately page our on-call incident responders to get you the help you need without delay.


Screenshot on the Under Attack button in the Cloudflare dashboard


Screenshot of the Emergency Incident Response page in the Cloudflare dashboard

For proactive needs, you can also easily submit requests for security advisory services through the Cloudflare dashboard: 


Confirmation of the successful service request submission

How to engage with Cloudforce One 

To learn more about REACT, existing Enterprise customers can explore the dedicated Incident Response section in the Cloudflare dashboard. For new inquiries regarding proactive partnerships and retainers, please contact Cloudflare sales.

If you are facing an active security crisis and need the REACT team on the ground, please contact us immediately.

Forensic investigation environment strategies in the AWS Cloud

Post Syndicated from Sol Kavanagh original https://aws.amazon.com/blogs/security/forensic-investigation-environment-strategies-in-the-aws-cloud/

When a deviation from your secure baseline occurs, it’s crucial to respond and resolve the issue quickly and follow up with a forensic investigation and root cause analysis. Having a preconfigured infrastructure and a practiced plan for using it when there’s a deviation from your baseline will help you to extract and analyze the information needed to determine the impact, scope, and root cause of an incident and return to operations confidently.

Time is of the essence in understanding the what, how, who, where, and when of a security incident. You often hear of automated incident response, which has repeatable and auditable processes to standardize the resolution of incidents and accelerate evidence artifact gathering.

Similarly, having a standard, pristine, pre-configured, and repeatable forensic clean-room environment that can be automatically deployed through a template allows your organization to minimize human interaction, keep the larger organization separate from contamination, hasten evidence gathering and root cause analysis, and protect forensic data integrity. The forensic analysis process assists in data preservation, acquisition, and analysis to identify the root cause of an incident. This approach can also facilitate the presentation or transfer of evidence to outside legal entities or auditors. AWS CloudFormation templates—or other infrastructure as code (IaC) provisioning tools—help you to achieve these goals, providing your business with consistent, well-structured, and auditable results that allow for a better overall security posture. Having these environments as a permanent part of your infrastructure allows them to be well documented and tested, and gives you opportunities to train your teams in their use.

This post provides strategies that you can use to prepare your organization to respond to secure baseline deviations. These strategies take the form of best practices around Amazon Web Services (AWS) account structure, AWS Organizations organizational units (OUs) and service control policies (SCPs), forensic Amazon Virtual Private Cloud (Amazon VPC) and network infrastructure, evidence artifacts to be collected, AWS services to be used, forensic analysis tool infrastructure, and user access and authorization to the above. The specific focus is to provide an environment where Amazon Elastic Compute Cloud (Amazon EC2) instances with forensic tooling can be used to examine evidence artifacts.

This post presumes that you already have an evidence artifact collection procedure or that you are implementing one and that the evidence can be transferred to the accounts described here. If you are looking for advice on how to automate artifact collection, see How to automate forensic disk collection for guidance.

Infrastructure overview

A well-architected multi-account AWS environment is based on the structure provided by Organizations. As companies grow and need to scale their infrastructure with multiple accounts, often in multiple AWS Regions, Organizations offers programmatic creation of new AWS accounts combined with central management and governance that helps them to do so in a controlled and standardized manner. This programmatic, centralized approach should be used to create the forensic investigation environments described in the strategy in this blog post.

The example in this blog post uses a simplified structure with separate dedicated OUs and accounts for security and forensics, shown in Figure 1. Your organization’s architecture might differ, but the strategy remains the same.

Note: There might be reasons for forensic analysis to be performed live within the compromised account itself, such as to avoid shutting down or accessing the compromised instance or resource; however, that approach isn’t covered here.

Figure 1: AWS Organizations forensics OU example

Figure 1: AWS Organizations forensics OU example

The most important components in Figure 1 are:

  • A security OU, which is used for hosting security-related access and services. The security OU and the associated AWS accounts should be owned and managed by your security organization.
  • A forensics OU, which should be a separate entity, although it can have some similarities and crossover responsibilities with the security OU. There are several reasons for having it within a separate OU and account. Some of the more important reasons are that the forensics team might be a different team than the security team (or a subset of it), certain investigations might be under legal hold with additional access restrictions, or a member of the security team could be the focus of an investigation.

When speaking about Organizations, accounts, and the permissions required for various actions, you must first look at SCPs, a core functionality of Organizations. SCPs offer control over the maximum available permissions for all accounts in your organization. In the example in this blog post, you can use SCPs to provide similar or identical permission policies to all the accounts under the forensics OU, which is being used as a resource container. This policy overrides all other policies, and is a crucial mechanism to ensure that you can explicitly deny or allow any API calls desired. Some use cases of SCPs are to restrict the ability to disable AWS CloudTrail, restrict root user access, and ensure that all actions taken in the forensic investigation account are logged. This provides a centralized way to avoid changing individual policies for users, groups, or roles. Accessing the forensic environment should be done using a least-privilege model, with nobody capable of modifying or compromising the initially collected evidence. For an investigation environment, denying all actions except those you want to list as exceptions is the most straightforward approach. Start with the default of denying all, and work your way towards the least authorizations needed to perform the forensic processes established by your organization. AWS Config can be a valuable tool to track the changes made to the account and provide evidence of these changes.

Keep in mind that once the restrictive SCP is applied, even the root account or those with administrator access won’t have access beyond those permissions; therefore, frequent, proactive testing as your environment changes is a best practice. Also, be sure to validate which principals can remove the protective policy, if required, to transfer the account to an outside entity. Finally, create the environment before the restrictive permissions are applied, and then move the account under the forensic OU.

Having a separate AWS account dedicated to forensic investigations is best to keep your larger organization separate from the possible threat of contamination from the incident itself, ensure the isolation and protection of the integrity of the artifacts being analyzed, and keeping the investigation confidential. Separate accounts also avoid situations where the threat actors might have used all the resources immediately available to your compromised AWS account by hitting service quotas and so preventing you from instantiating an Amazon EC2 instance to perform investigations.

Having a forensic investigation account per Region is also a good practice, as it keeps the investigative capabilities close to the data being analyzed, reduces latency, and avoids issues of the data changing regulatory jurisdictions. For example, data residing in the EU might need to be examined by an investigative team in North America, but the data itself cannot be moved because its North American architecture doesn’t align with GDPR compliance. For global customers, forensics teams might be situated in different locations worldwide and have different processes. It’s better to have a forensic account in the Region where an incident arose. The account as a whole could also then be provided to local legal institutions or third-party auditors if required. That said, if your AWS infrastructure is contained within Regions only in one jurisdiction or country, then a single re-creatable account in one Region with evidence artifacts shared from and kept in their respective Regions could be an easier architecture to manage over time.

An account created in an automated fashion using a CloudFormation template—or other IaC methods—allows you to minimize human interaction before use by recreating an entirely new and untouched forensic analysis instance for each separate investigation, ensuring its integrity. Individual people will only be given access as part of a security incident response plan, and even then, permissions to change the environment should be minimal or none at all. The post-investigation environment would then be either preserved in a locked state or removed, and a fresh, blank one created in its place for the subsequent investigation with no trace of the previous artifacts. Templating your environment also facilitates testing to ensure your investigative strategy, permissions, and tooling will function as intended.

Accessing your forensics infrastructure

Once you’ve defined where your investigative environment should reside, you must think about who will be accessing it, how they will do so, and what permissions they will need.

The forensic investigation team can be a separate team from the security incident response team, the same team, or a subset. You should provide precise access rights to the group of individuals performing the investigation as part of maintaining least privilege.

You should create specific roles for the various needs of the forensic procedures, each with only the permissions required. As with SCPs and other situations described here, start with no permissions and add authorizations only as required while establishing and testing your templated environments. As an example, you might create the following roles within the forensic account:

Responder – acquire evidence

Investigator – analyze evidence

Data custodian – manage (copy, move, delete, and expire) evidence

Analyst – access forensics reports for analytics, trends, and forecasting (threat intelligence)

You should establish an access procedure for each role, and include it in the response plan playbook. This will help you ensure least privilege access as well as environment integrity. For example, establish a process for an owner of the Security Incident Response Plan to verify and approve the request for access to the environment. Another alternative is the two-person rule. Alert on log-in is an additional security measure that you can add to help increase confidence in the environment’s integrity, and to monitor for unauthorized access.

You want the investigative role to have read-only access to the original evidence artifacts collected, generally consisting of Amazon Elastic Block Store (Amazon EBS) snapshots, memory dumps, logs, or other artifacts in an Amazon Simple Storage Service (Amazon S3) bucket. The original sources of evidence should be protected; MFA delete and S3 versioning are two methods for doing so. Work should be performed on copies of copies if rendering the original immutable isn’t possible, especially if any modification of the artifact will happen. This is discussed in further detail below.

Evidence should only be accessible from the roles that absolutely require access—that is, investigator and data custodian. To help prevent potential insider threat actors from being aware of the investigation, you should deny even read access from any roles not intended to access and analyze evidence.

Protecting the integrity of your forensic infrastructures

Once you’ve built the organization, account structure, and roles, you must decide on the best strategy inside the account itself. Analysis of the collected artifacts can be done through forensic analysis tools hosted on an EC2 instance, ideally residing within a dedicated Amazon VPC in the forensics account. This Amazon VPC should be configured with the same restrictive approach you’ve taken so far, being fully isolated and auditable, with the only resources being dedicated to the forensic tasks at hand.

This might mean that the Amazon VPC’s subnets will have no internet gateways, and therefore all S3 access must be done through an S3 VPC endpoint. VPC flow logging should be enabled at the Amazon VPC level so that there are records of all network traffic. Security groups should be highly restrictive, and deny all ports that aren’t related to the requirements of the forensic tools. SSH and RDP access should be restricted and governed by auditable mechanisms such as a bastion host configured to log all connections and activity, AWS Systems Manager Session Manager, or similar.

If using Systems Manager Session Manager with a graphical interface is required, RDP or other methods can still be accessed. Commands and responses performed using Session Manager can be logged to Amazon CloudWatch and an S3 bucket, this allows auditing of all commands executed on the forensic tooling Amazon EC2 instances. Administrative privileges can also be restricted if required. You can also arrange to receive an Amazon Simple Notification Service (Amazon SNS) notification when a new session is started.

Given that the Amazon EC2 forensic tooling instances might not have direct access to the internet, you might need to create a process to preconfigure and deploy standardized Amazon Machine Images (AMIs) with the appropriate installed and updated set of tooling for analysis. Several best practices apply around this process. The OS of the AMI should be hardened to reduce its vulnerable surface. We do this by starting with an approved OS image, such as an AWS-provided AMI or one you have created and managed yourself. Then proceed to remove unwanted programs, packages, libraries, and other components. Ensure that all updates and patches—security and otherwise—have been applied. Configuring a host-based firewall is also a good precaution, as well as host-based intrusion detection tools. In addition, always ensure the attached disks are encrypted.

If your operating system is supported, we recommend creating golden images using EC2 Image Builder. Your golden image should be rebuilt and updated at least monthly, as you want to ensure it’s kept up to date with security patches and functionality.

EC2 Image Builder—combined with other tools—facilitates the hardening process; for example, allowing the creation of automated pipelines that produce Center for Internet Security (CIS) benchmark hardened AMIs. If you don’t want to maintain your own hardened images, you can find CIS benchmark hardened AMIs on the AWS Marketplace.

Keep in mind the infrastructure requirements for your forensic tools—such as minimum CPU, memory, storage, and networking requirements—before choosing an appropriate EC2 instance type. Though a variety of instance types are available, you’ll want to ensure that you’re keeping the right balance between cost and performance based on your minimum requirements and expected workloads.

The goal of this environment is to provide an efficient means to collect evidence, perform a comprehensive investigation, and effectively return to safe operations. Evidence is best acquired through the automated strategies discussed in How to automate incident response in the AWS Cloud for EC2 instances. Hashing evidence artifacts immediately upon acquisition is highly recommended in your evidence collection process. Hashes, and in turn the evidence itself, can then be validated after subsequent transfers and accesses, ensuring the integrity of the evidence is maintained. Preserving the original evidence is crucial if legal action is taken.

Evidence and artifacts can consist of, but aren’t limited to:

Access to the control plane logs mentioned above—such as the CloudTrail logs—can be accessed in one of two ways. Ideally, the logs should reside in a central location with read-only access for investigations as needed. However, if not centralized, read access can be given to the original logs within the source account as needed. Read access to certain service logs found within the security account, such as AWS Config, Amazon GuardDuty, Security Hub, and Amazon Detective, might be necessary to correlate indicators of compromise with evidence discovered during the analysis.

As previously mentioned, it’s imperative to have immutable versions of all evidence. This can be achieved in many ways, including but not limited to the following examples:

  • Amazon EBS snapshots, including hibernation generated memory dumps:
    • Original Amazon EBS disks are snapshotted, shared to the forensics account, used to create a volume, and then mounted as read-only for offline analysis.
  • Amazon EBS volumes manually captured:
    • Linux tools such as dc3dd can be used to stream a volume to an S3 bucket, as well as provide a hash, and then made immutable using an S3 method from the next bullet point.
  • Artifacts stored in an S3 bucket, such as memory dumps and other artifacts:
    • S3 Object Lock prevents objects from being deleted or overwritten for a fixed amount of time or indefinitely.
    • Using MFA delete requires the requestor to use multi-factor authentication to permanently delete an object.
    • Amazon S3 Glacier provides a Vault Lock function if you want to retain immutable evidence long term.
  • Disk volumes:
    • Linux: Mount in read-only mode.
    • Windows: Use one of the many commercial or open-source write-blocker applications available, some of which are specifically made for forensic use.
  • CloudTrail:
  • AWS Systems Manager inventory:
  • AWS Config data:
    • By default, AWS Config stores data in an S3 bucket, and can be protected using the above methods.

Note: AWS services such as KMS can help enable encryption. KMS is integrated with AWS services to simplify using your keys to encrypt data across your AWS workloads.

An example use case of Amazon EBS disks being shared as evidence to the forensics account, the following figure—Figure 2—is a simplified S3 bucket folder structure you could use to store and work with evidence.

Figure 2 shows an S3 bucket structure for a forensic account. An S3 bucket and folder is created to hold incoming data—for example, from Amazon EBS disks—which is streamed to Incoming Data > Evidence Artifacts using dc3dd. The data is then copied from there to a folder in another bucket—Active Investigation > Root Directory > Extracted Artifacts—to be analyzed by the tooling installed on your forensic Amazon EC2 instance. Also, there are folders under Active Investigation for any investigation notes you make during analysis, as well as the final reports, which are discussed at the end of this blog post. Finally, a bucket and folders for legal holds, where an object lock will be placed to hold evidence artifacts at a specific version.

Figure 2: Forensic account S3 bucket structure

Figure 2: Forensic account S3 bucket structure

Considerations

Finally, depending on the severity of the incident, your on-premises network and infrastructure might also be compromised. Having an alternative environment for your security responders to use in case of such an event reduces the chance of not being able to respond in an emergency. Amazon services such as Amazon Workspaces—a fully managed persistent desktop virtualization service—can be used to provide your responders a ready-to-use, independent environment that they can use to access the digital forensics and incident response tools needed to perform incident-related tasks.

Aside from the investigative tools, communications services are among the most critical for coordination of response. You can use Amazon WorkMail and Amazon Chime to provide that capability independent of normal channels.

Conclusion

The goal of a forensic investigation is to provide a final report that’s supported by the evidence. This includes what was accessed, who might have accessed it, how it was accessed, whether any data was exfiltrated, and so on. This report might be necessary for legal circumstances, such as criminal or civil investigations or situations requiring breach notifications. What output each circumstance requires should be determined in advance in order to develop an appropriate response and reporting process for each. A root cause analysis is vital in providing the information required to prepare your resources and environment to help prevent a similar incident in the future. Reports should not only include a root cause analysis, but also provide the methods, steps, and tools used to arrive at the conclusions.

This article has shown you how you can get started creating and maintaining forensic environments, as well as enable your teams to perform advanced incident resolution investigations using AWS services. Implementing the groundwork for your forensics environment, as described above, allows you to use automated disk collection to begin iterating on your forensic data collection capabilities and be better prepared when security events occur.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on one of the AWS Security, Identity, and Compliance forums or contact AWS Support.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Author

Sol Kavanagh

Sol is a senior solutions architect and CISSP with 20+ years of experience in the enterprise space. He is passionate about security and helping customers build solutions in the AWS Cloud. In his spare time he enjoys distance cycling, adventure travelling, Buddhist philosophy, and Muay Thai.