Post Syndicated from Techmoan original https://www.youtube.com/watch?v=4VzT2e8rvY0
Minisforum MS-01 Launched 10GbE Mini PC First Look
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/minisforum-ms-01-launched-10gbe-mini-pc-first-look/
Ahead of our full review, we have a quick look at the Minisforum MS-01, the SFP+ 10GbE system with a lot of cool features
The post Minisforum MS-01 Launched 10GbE Mini PC First Look appeared first on ServeTheHome.
Metasploit 2023 Wrap-Up
Post Syndicated from Spencer McIntyre original https://blog.rapid7.com/2023/12/29/metasploit-2023-wrap-up/
As 2023 winds down, we’re taking another look back at all the changes and improvements to the Metasploit Framework. This year marked the 20th anniversary since Metasploit version 1.0 was committed and the project is still actively maintained and improved thanks to a thriving community.
Version 6.3
Early this year in January, Metasploit version 6.3 was released with a number of improvements for targeting Active Directory environments. The crowning achievement of this effort was the integration of native Kerberos authentication. With this in place, HTTP, LDAP, MSSQL, SMB and WinRM modules can all make use of Kerberos authentication, enabling a swath of new attack techniques and workflows. In addition to the existing modules that are now capable of authenticating with Kerberos, multiple Kerberos-specific modules were added as well for a variety of tasks such as requesting tickets from the Key Distribution Center (aka the KDC which is almost always the Active Directory Domain Controller), forging tickets from known secrets, and inspecting the contents of tickets.
This functionality was highlighted in Black Hat USA’s Arsenal demonstrations, a recording of which can be found online.
Fetch Based Payloads
In May 2023, Metasploit released a new set of payloads, dubbed the Fetch Payloads which make exploitation of OS-command-executing vulnerabilities easier for users. At the time of the release, about two-thirds of exploits added to the Metasploit Framework in the previous year resulted in the execution of an OS command, either due to direct injection or via some other means such as deserialization. While OS command execution is becoming more popular, it often limits the type of payloads that can easily be added to an exploit since the most advanced payloads, including Meterpreter, aren’t available as OS commands.
Prior to the Fetch Payloads, exploit authors were burdened with the work necessary to convert Meterpreter payloads to something deliverable as an OS command. This led to extra work and inconsistent implementations that often lacked the flexibility our users desire. The new pattern uses the Fetch Payloads, which allows the Framework to handle this automatically. The result is less work for exploit developers and a higher degree of control for end users. We expect to see Fetch Payloads continue to be used widely well past 2024 and to have new variants added.
Even More Kerberos Improvements
While the Metasploit 6.3 release provided support for native Kerberos authentication for Metasploit, we’ve since built on it to add even more. These features didn’t make it into the original 6.3 release in January but have since shipped in weekly releases:
- The
auxiliary/admin/kerberos/forge_ticketmodule was expanded to support the diamond and sapphire techniques in addition to the original golden and silver techniques. - The
auxiliary/admin/kerberos/forge_ticketmodule was also updated to account for the additional fields used by Windows Server 2022, enabling its compatibility with the latest Windows targets. - We added the
post/windows/manage/kerberos_ticketspost module, which enables users to dump Kerberos tickets from a compromised host. This is similar functionality to what the popular Rubeus tool’sklist/dumpcommands do and operates entirely in memory. With this in place, users can now exploit instances of Unconstrained Delegation. - The
auxiliary/gather/windows_secrets_dumpmodule was updated to support pass-the-ticket authentication when using the DCSync technique (theDOMAINaction). This enables users to dump all of the secrets from the target given only a valid Kerberos ticket with the required permissions instead of requiring authentication by username and password.
Fewer DNS Leaks
One of the best features of Metasploit is the seamless way in which users can use established Meterpreter and SSH sessions to tunnel traffic as configured by the route command or often the post/multi/manage/autoroute module. Until this year, these connections would resolve hostnames to IP addresses from the system on which the Metasploit Framework was running, which could potentially leak information to listening parties. Thanks to a combined effort by sempervictus and smashery, Metasploit can now be configured to use a custom DNS server that is optionally accessed via an established session. This feature is currently behind a feature flag and requires users to run features set dns_feature true before it can be accessed.
Once enabled, the dns command allows users to configure how they would like to resolve DNS hostnames. Users can simply specify a single server to handle all queries, or use a wildcard syntax to send DNS queries for one domain to a specific server and non-matching queries to another. The weekly wrap up for the original release contains more detailed notes and usage examples.
Discoverability Improvements
A more recent change to the Framework brought a new feature to allow searching for more fields within modules. By enabling hierarchical search with features set hierarchical_search_table true, users will now find search queries that match module actions, targets, and AKA aliases. For example, this will cause the auxiliary/admin/kerberos/forge_ticket module to be included in the search results when forge_golden is the query because forging golden tickets is one of the actions that it supports.
Users can also discover new capabilities and how to use them by browsing our new docs site at docs.metasploit.com. This site’s source code is included within Metasploit itself, making it easy for users to contribute improvements and their own workflows.
Payload Improvements
Exploits are at the core of what we do on the Metasploit team, but they would be nothing without our payloads. This year saw multiple improvements to our payloads — some changes closed feature gaps, while others added net new functionality. Some highlights include:
- Smashery updated our Java Meterpreter payloads with an important fix to the loader to enable compatibility with the latest versions of OpenJDK.
- Salu90 added a new API to the Windows Meterpreter and a post module to use it that allows users to set the session’s token to a new value.
- JustAnda7 updated the Windows Meterpreter to display IPv6 routes for inspection when the user runs the Meterpreter
routecommand (not to be confused with the Frameworkroutecommand). - Ishaanahuja7 added support to Meterpreter for running natively on Apple’s new ARM-based chips.
- Sempervictus added native sessions for AWS Instance connections and AWS SSM agents. These session types are noteworthy because while they require access tokens, they do not require a payload to be run on the target and can be used to open a session on a target that Metasploit is otherwise unable to communicate with.
- usiegl00 and Ishaanahuja7 both contributed enhancements to add support OSX AArch64 Meterpreter payloads, which enables the use of native payloads on M1 or M2 OSX devices that do not have Rosetta installed.
Additionally, GitHub Actions are now being used to measure the feature coverage of the Meterpreter API commands. It’s a lesser-known fact that the Meterpreter payload has multiple implementations for different architectures and platforms. This means some features may be present in one and not another. This is the reason the Mimikatz kiwi plugin isn’t available when the java/meterpreter/reverse_tcp payload is used. To help us and the community track this information, a report including a coverage matrix is now generated automatically. This report can be accessed by navigating to the project’s Actions tab, selecting “Acceptance”, the latest run, and finally downloading the “final-report”.
Module Highlights
-
CVE-2022-47966 – This particular vulnerability was an RCE in multiple ManageEngine products. A combined effort by cdelafuente-r7 and h00die-grey brought exploits for the ServiceDesk Plus, ADSelfService Plus, and Endpoint Central products.
-
CVE-2023-34362 (Exploit) – The MOVEit exploit leverages one of the more high-profile vulnerabilities to have been released this year. This module exploits a SQL injection to leak sensitive data in order to upload a .NET deserialization payload which results in code execution in the context of NT AUTHORITY\ SYSTEM and was a combined effort by sfewer-r7, rbowes-r7, and bwatters-r7.
-
CVE-2023-32560 (Exploit) – This vulnerability is an unauthenticated RCE in Ivanti Avalanche MDM that would result in code execution as NT AUTHORITY\SYSTEM. The module was submitted by EgeBalci and is one of the very few memory corruption exploits added this year.
-
CVE-2023-46214 (Exploit) – Chocapikk made their first contributions this year, one of which is for an authenticated RCE in Splunk Enterprise.
-
CVE-2023-22952
(Exploit) – This exploit was contributed by community member h00die-gr3y back in January of 2023. While it may seem like old news nearly a year later, this zero-day gained a lot of attention when it first came to light. This exploit brought along with it new mixin capabilities for Metasploit to embed PHP payloads in PNG images. This opens the door for future exploit modules to drop payloads inside of PNGs with ease. -
CVE-2023-20887
(Exploit) – This module was added by community contributor sinsinology (with help from community contributor h00die). There were a few Metasploit modules released this year that targeted VMware products; however this one stands out above the rest. Targeting the popular VMware Aria Operations for Networks software, this module enabled attackers to gain unauthenticated code execution in the context of the root user on a wide range of affected software versions. -
CVE-2023-27350
(Exploit) – Speaking of modules written for celebrity vulnerabilities, let’s not leave out the PaperCut NG Authentication Bypass, brought to the framework by Metasploit’s one and only Christophe De La Fuente. Christophe’s contribution helped pen testers better assess the security of systems hosting PaperCut NG and ease the concerns of their clients during a stressful time in the cybersecurity ecosystem. The module exploits all affected versions of PaperCut NG and returns an elevated Meterpreter session. -
Post Module – Written by Spencer McIntyre of the Metasploit team, this module highlights the framework’s new, powerful Kerberos capabilities. Bringing along with it a large amount of railgun enhancements this module allows for Kerberos tickets to be exported from a compromised host and added to Metasploit’s own cache, allowing them to be used in subsequent attacks. The Kerberos work along with this module helps streamline many different types of attacks that can be performed in and around Domain environments. If you haven’t tested Metasploit’s Kerberos authentication capabilities yet, put it at the top of your todo list for 2024!
-
CVE-2023-28252
(Exploit) – The Common Log File System (CLFS) driver is a fantastic vector for attacks; it’s installed on all the latest versions of Windows and saw more abuse in 2023. Ransomware gangs exploited this vulnerability to gain SYSTEM level access on Windows 10, 11 and Server 2022. Metasploit team member Jack Heysel wrote this module that uses the Reflective DLL template in order to drop a low level PoC which returns a session running in the context of NT AUTHORITY\SYSTEM. -
CVE-2023-40044
(Exploit) – Another exploit that made big waves this year was the WS_FTP server running the Ad Hoc Transfer module .NET deserialization vulnerability. The module and the initial research behind how the vulnerability actually works was brought to us by Metasploit’s very own, veteran contributor, Stephen Fewer. The exploit module runs reliably on a wide range of affected targets. Everyone loves a module where all you have to do is: select the module, input the IP address of the machine running the vulnerable software, run the module, and get a SYSTEM-level session.
Contributors
We would like to give a big thank you to all of the contributors who sent us code in 2023. Whether it was bug fixes, enhancements, or exploits, we appreciate the work you put into making Metasploit better. In 2023, we received pull requests from the following 75 people (ordered by count). Of these, 49 made their first contribution to Metasploit this year.
- h00die
- bcoles
- smashery
- h00die-gr3y
- jmartin-tech
- ErikWynter
- EgeBalci
- ismaildawoodjee (new in 2023)
- wvu
- jvoisin
- sempervictus
- rorymckinley (new in 2023)
- rad10
- manishkumarr1017 (new in 2023)
- Ryuuuuu (new in 2023)
- prabhatjoshi321 (new in 2023)
- Chocapikk (new in 2023)
- Jemmy1228 (new in 2023)
- AleksaZatezalo (new in 2023)
- emirpolatt (new in 2023)
- heyder
- steve-embling
- dm-ct (new in 2023)
- ide0x90
- archcloudlabs
- samsepi0x0 (new in 2023)
- Lorenyx (new in 2023)
- MikeAnast (new in 2023)
- loredous (new in 2023)
- bradyjackson (new in 2023)
- nfsec
- HynekPetrak
- whotwagner (new in 2023)
- rtpt-erikgeiser
- errorxyz (new in 2023)
- e-lliot (new in 2023)
- gcarmix (new in 2023)
- j0ev (new in 2023)
- xaitax (new in 2023)
- cudalac (new in 2023)
- bka-dev
- cnnrshd (new in 2023)
- pbarry25 (new in 2023)
- D00Movenok (new in 2023)
- gardnerapp (new in 2023)
- rodnt (new in 2023)
- hahwul (new in 2023)
- JustAnda7
- Guilhem7 (new in 2023)
- shellchocolat (new in 2023)
- sdcampbell (new in 2023)
- attl4s (new in 2023)
- distortedsignal (new in 2023)
- spmedia (new in 2023)
- YiDa858 (new in 2023)
- j-baines (new in 2023)
- catatonicprime
- vtoutain (new in 2023)
- SubcomandanteMeowcos (new in 2023)
- samueloph (new in 2023)
- araout42 (new in 2023)
- Pflegusch (new in 2023)
- tekwizz123
- rohitkumarankam (new in 2023)
- jeffmcjunkin
- MegaManSec
- bugch3ck
- raboof (new in 2023)
- JBince (new in 2023)
- Frycos (new in 2023)
- neterum (new in 2023)
- mkonda (new in 2023)
- serializingme (new in 2023)
- k0pak4
- npm-cesium137-io
- hamax97 (new in 2023)
AWS successfully renews GSMA security certification for US East (Ohio) and Europe (Paris) Regions
Post Syndicated from Janice Leung original https://aws.amazon.com/blogs/security/aws-successfully-renews-gsma-security-certification-for-us-east-ohio-and-europe-paris-regions-2/
Amazon Web Services is pleased to announce that the AWS US East (Ohio) and Europe (Paris) Regions have been recertified through October 2024 by the GSM Association (GSMA) under its Security Accreditation Scheme for Subscription Management (SAS-SM) with scope Data Centre Operations and Management (DCOM).
The US East (Ohio) Region first obtained GSMA certification in September 2021, and the Europe (Paris) Region first obtained GSMA certification in October 2021. This renewal demonstrates our continuous commitment to adhere to the heightened expectations for cloud service providers. AWS customers who provide an embedded Universal Integrated Circuit Card (eUICC) for mobile devices can run their remote provisioning applications with confidence in the AWS Cloud in the GSMA-certified Regions.
For up-to-date information related to the certification, see the AWS Compliance Program page and choose GSMA under Europe, Middle East & Africa.
AWS was evaluated by independent third-party auditors that GSMA selected. The Certificate of Compliance that shows AWS achieved GSMA compliance status is available on the GSMA website and through AWS Artifact. AWS Artifact is a self-service portal for on-demand access to AWS compliance reports. Sign in to AWS Artifact in the AWS Management Console, or learn more at Getting Started with AWS Artifact.
To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page. If you have feedback about this post, submit comments in the Comments section below.
Want more AWS Security news? Follow us on Twitter.
Velociraptor 0.7.1 Release: Sigma Support, ETW Multiplexing, Local Encrypted Storage and New VQL Capabilities Highlight the Last Release of 2023
Post Syndicated from Rapid7 original https://blog.rapid7.com/2023/12/29/velociraptor-0-7-1-release-sigma-support-etw-multiplexing-local-encrypted-storage-and-new-vql-capabilities-highlight-the-last-release-of-2023/
Written by Dr. Michael Cohen
Rapid7 is excited to announce that version 0.7.1 of Velociraptor is live and available for download. There are several new features and capabilities that add to the power and efficiency of this open-source digital forensic and incident response (DFIR) platform.
In this post, Rapid7 Digital Paleontologist, Dr. Mike Cohen discusses some of the exciting new features.
GUI improvements
The GUI was updated in this release to improve user workflow and accessibility.
Notebook improvements
Velociraptor uses notebooks extensively to facilitate collaboration, and post processing. There are currently three types of notebooks:
- Global Notebooks – these are available from the GUI sidebar and can be shared with other users for a collaborative workflow.
- Collection notebooks – these are attached to specific collections and allow post processing the collection results.
- Hunt notebooks – are attached to a hunt and allow post processing of the collection data from a hunt.
This release further develops the Global notebooks workflow as a central place for collecting and sharing analysis results.
Templated notebooks
Many users use notebooks heavily to organize their investigation and guide users on what to collect. While Collection notebooks and Hunt notebooks can already include templates there was no way to customize the default Global notebook.
In this release, we define a new type of Artifact of type NOTEBOOK which allows a user to define a template for global notebooks.
In this example I will create such a template to help users gather server information about clients. I click on the artifact editor in the sidebar, then select Notebook Templates from the search screen. I then edit the built in Notebooks. Default artifact.
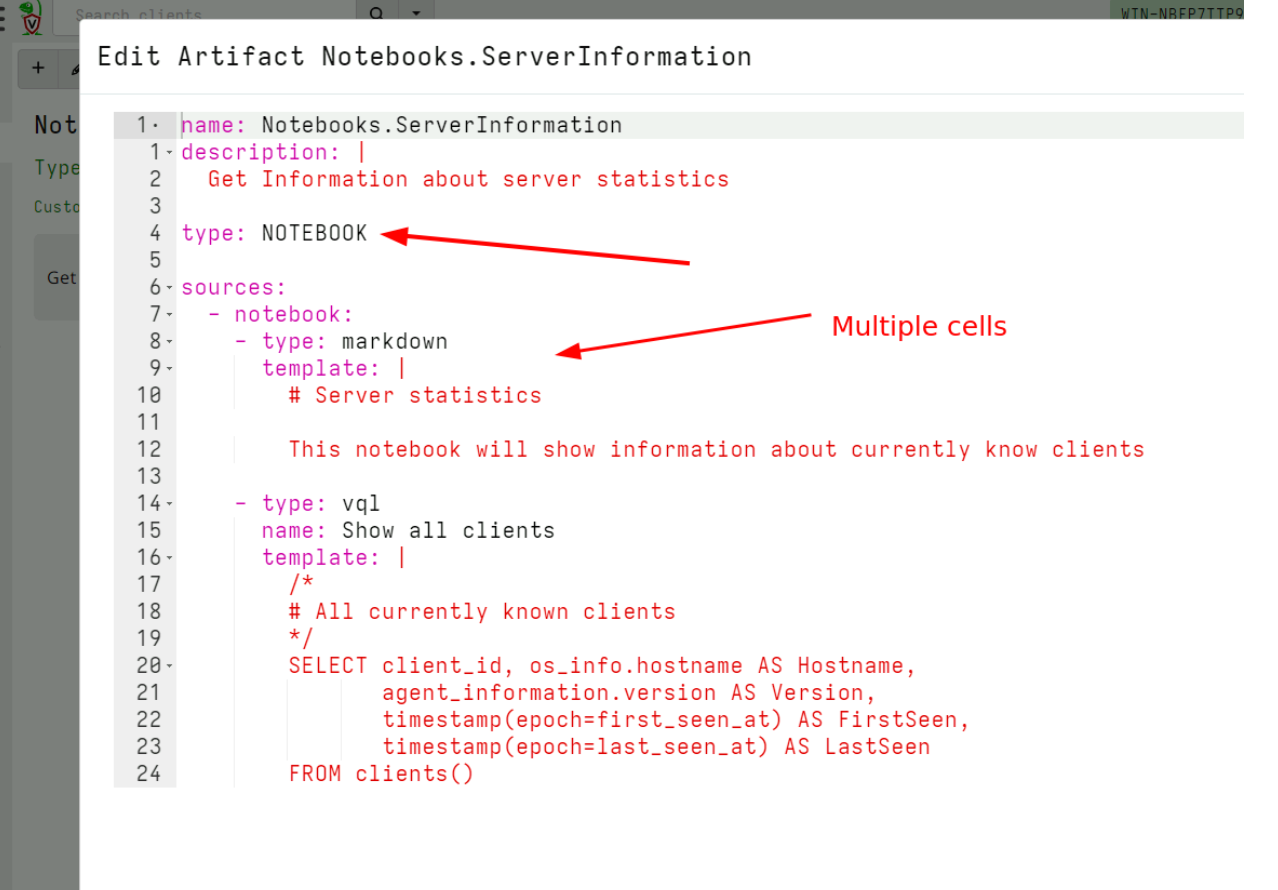
I can define multiple cells in the notebook. Cells can be of type vql, markdown or vql_suggestion. I usually use the markdown cells to write instructions for users of how to use my notebook, while vql cells can run queries like schedule collections or preset hunts.
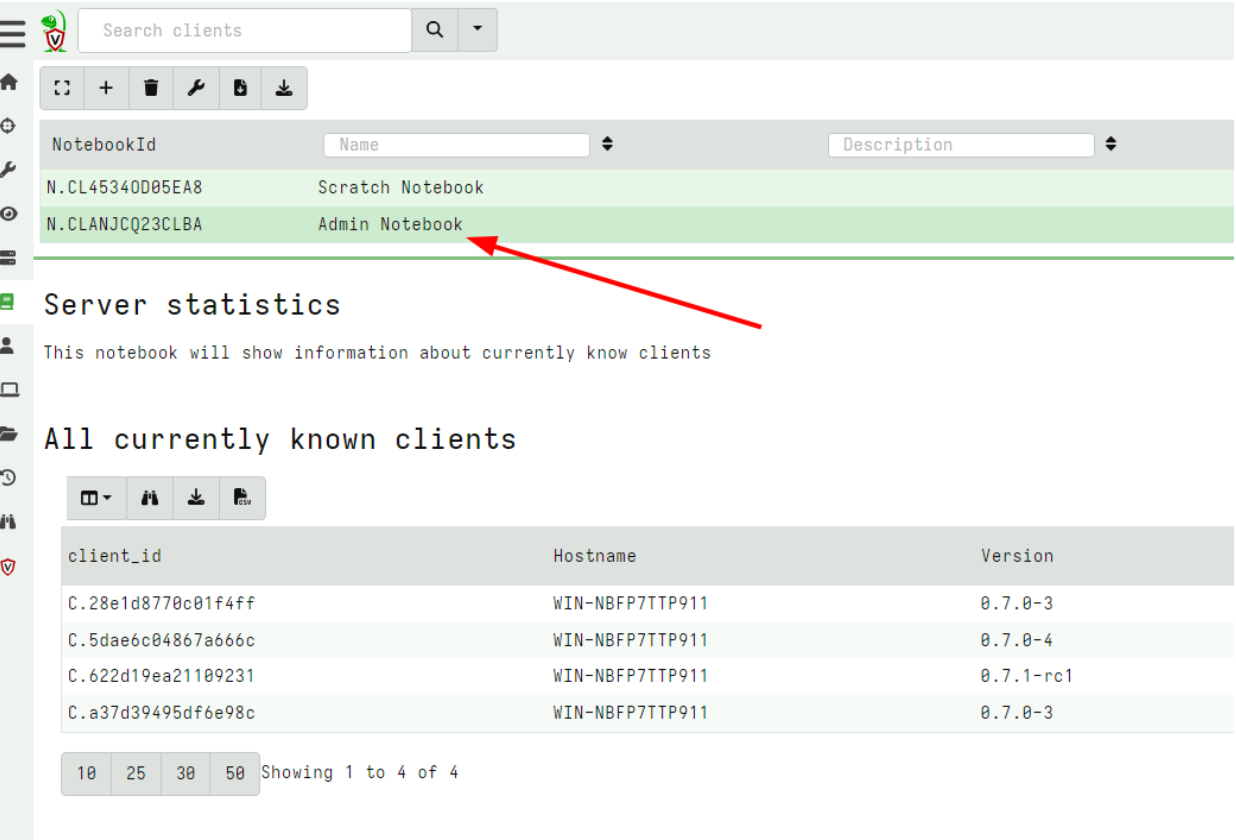
Next I select the Global notebooks in the sidebar and click the New Notebook button. This brings up a wizard that allows me to create a new global notebook. After filling in the name of the notebook and electing which user to share it with, I can choose the template for this notebook.
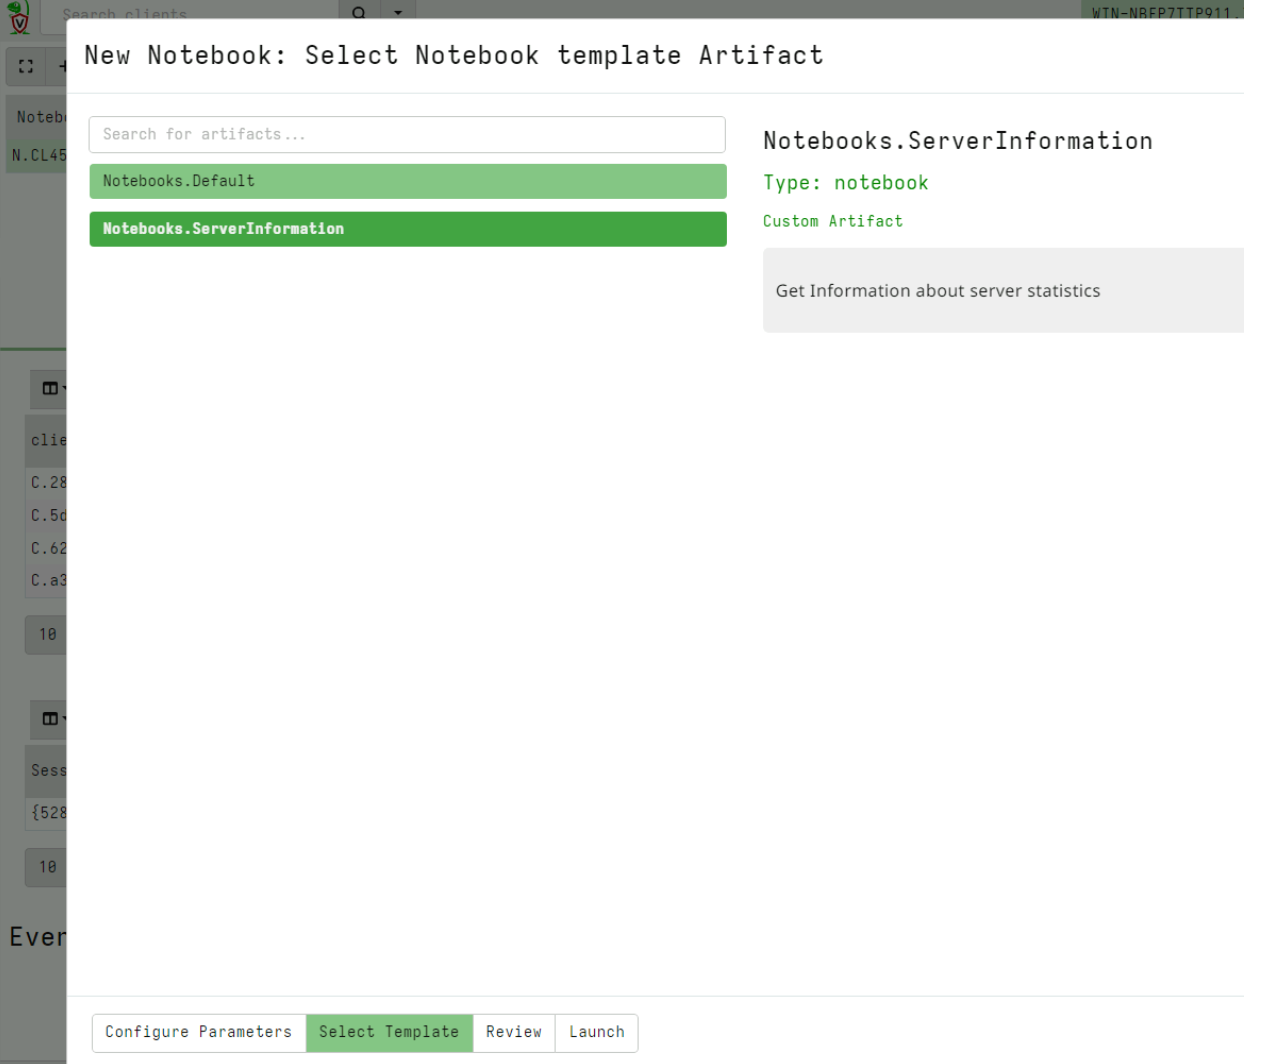
I can see my newly added notebook template and select it.
Copying notebook cells
In this release, Velociraptor allows copying of a cell from any notebook to the Global notebooks. This facilitates a workflow where users may filter, post-process and identify interesting artifacts in various hunt notebooks or specific collection notebooks, but then copy the post processed cell into a central Global notebook for collaboration.
For the next example, I collect the server artifact Server.Information.Clients and post process the results in the notebook to count the different clients by OS.
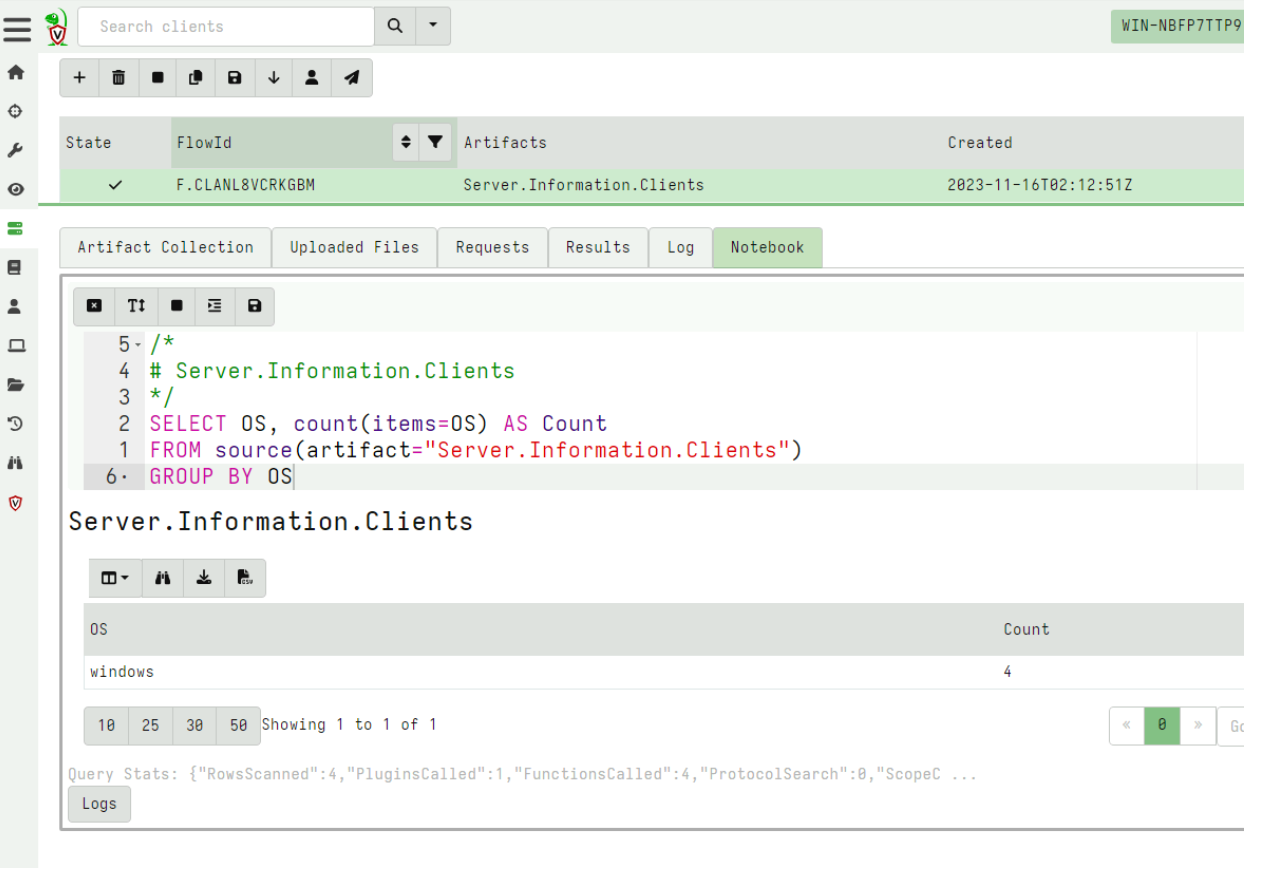
Now that I am happy with this query, I want to copy the cell to my Admin Notebook which I created earlier.
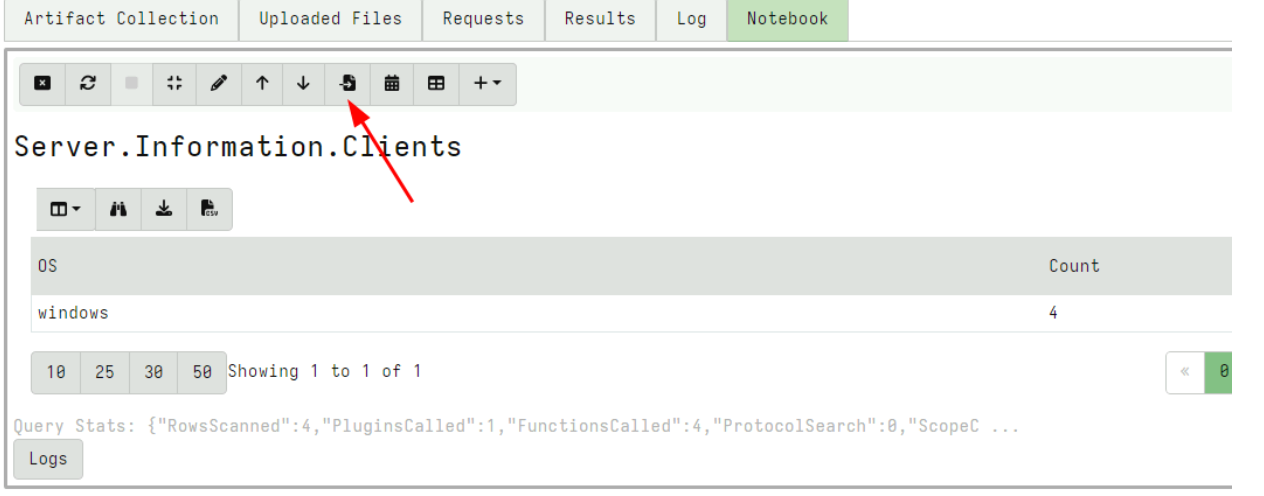
I can then select which Global notebook to copy the cell into.
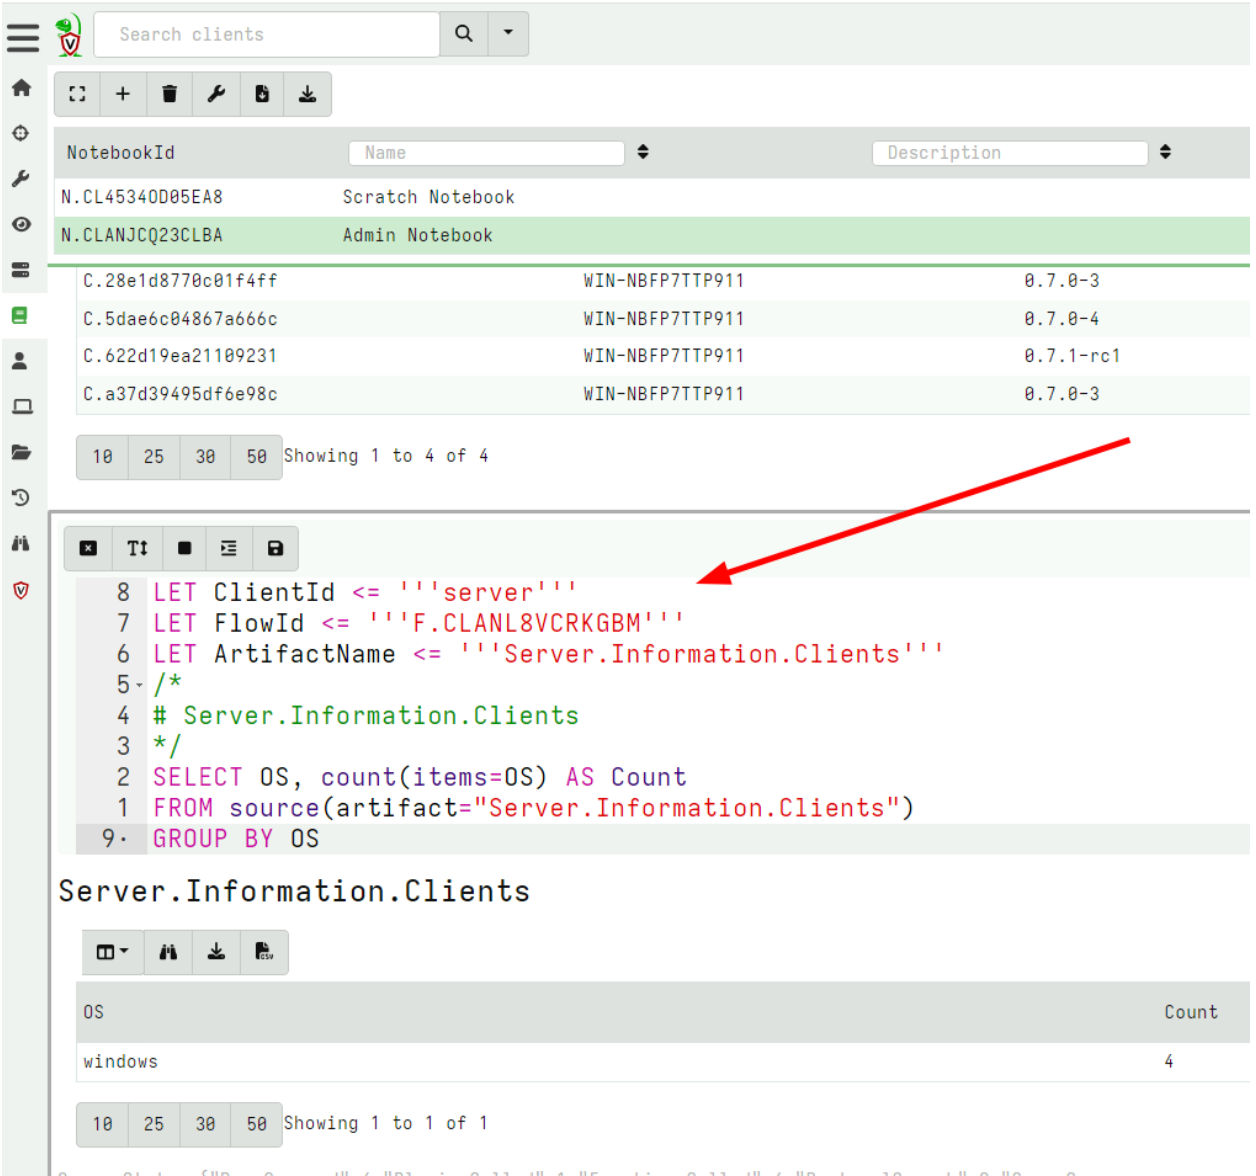
Velociraptor will copy the cell to the target notebook and add VQL statements to still refer to the original collection. This allows users of the global notebook to further refine the query if needed.
This workflow allows better collaboration between users.
VFS Downloads
Velociraptor’s VFS view is an interactive view of the endpoint’s filesystem. Users can navigate the remote filesystem using a familiar tree based navigation and interactively fetch various files from the endpoint.
Before the 0.7.1 release, the user was able to download and preview individual files in the GUI but it was difficult to retrieve multiple files downloaded into the VFS.
In the 0.7.1 release, there is a new GUI button to initiate a collection from the VFS itself. This allows the user to download all or only some of the files they had previously interactively downloaded into the VFS.
For example consider the following screenshot that shows a few files downloaded into the VFS.
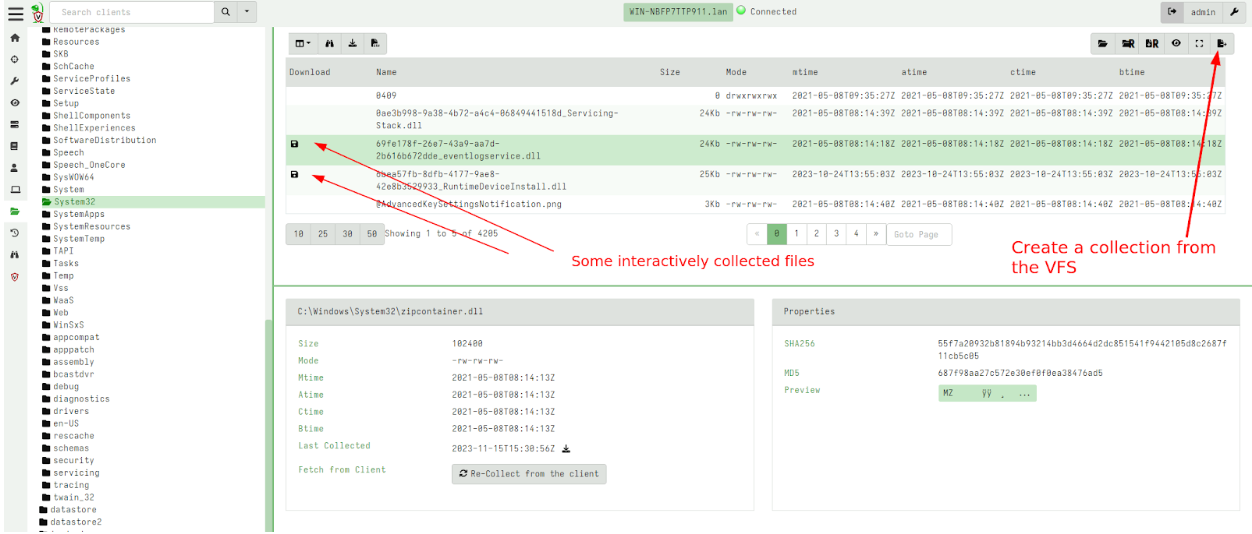
I can initiate a collection from the VFS. This is a server artifact (similar to the usual File Finder artifacts) that simply traverses the VFS with a glob uploading all files into a single collection.
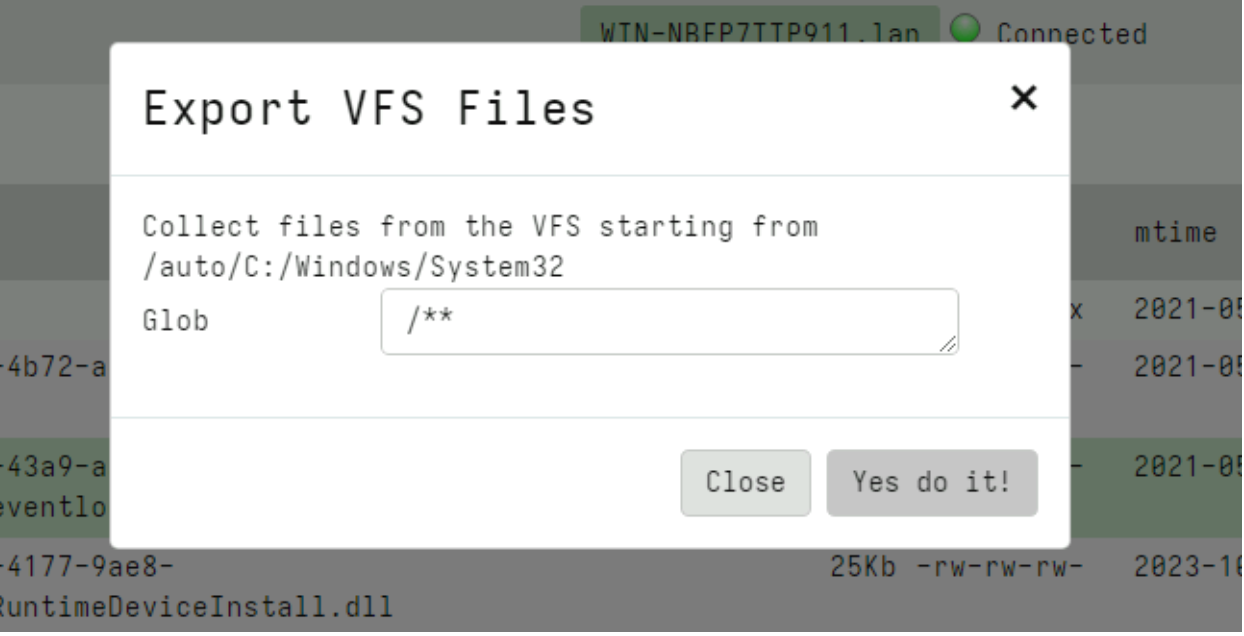
Using the glob I can choose to retrieve files with a particular filename pattern (e.g. only executables) or all files.
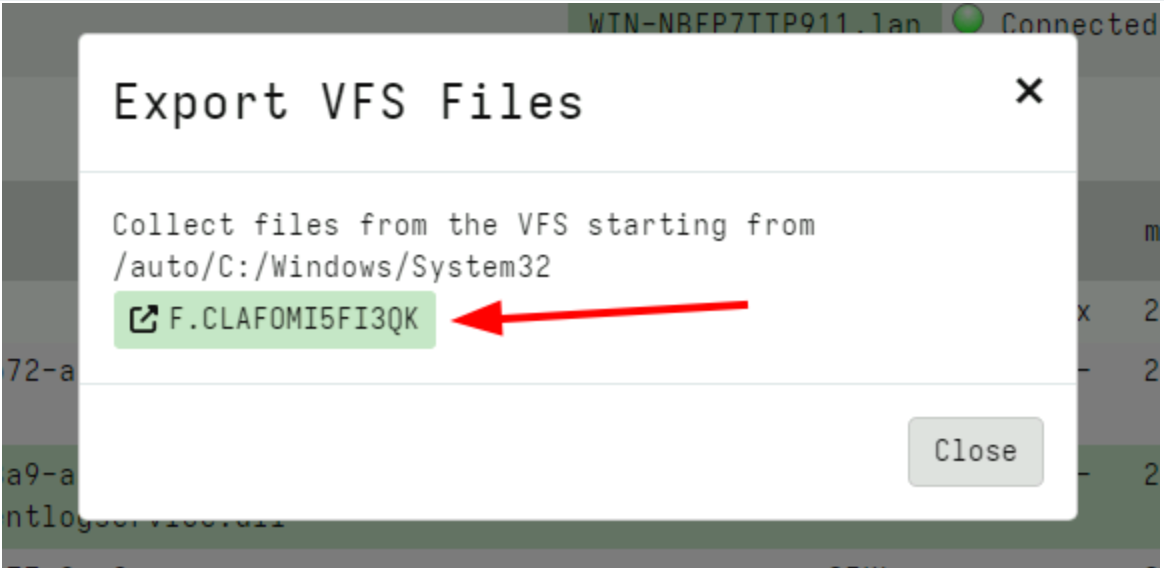
Finally the GUI shows a link to the collected flow where I can inspect the files or prepare a download zip just like any other collection.
New VQL plugins and capabilities
This release introduces an exciting new capability: Built-in Sigma Support.
Built-in Sigma Support
Sigma is fast emerging as a popular standard for writing and distributing detections. Sigma was originally designed as a portable notation for multiple backend SIEM products: Detections expressed in Sigma rules can be converted (compiled) into a target SIEM query language (for example into Elastic queries) to run on the target SIEM.
Velociraptor is not really a SIEM in the sense that we do not usually forward all events to a central storage location where large queries can run on it. Instead, Velociraptor’s philosophy is to bring the query to the endpoint itself.
In Velociraptor, Sigma rules can directly be used on the endpoint, without the need to forward all the events off the system first! This makes Sigma a powerful tool for initial triage:
- Apply a large number of Sigma rules on the local event log files.
- Those rules that trigger immediately surface potentially malicious activity for further scrutiny.
This can be done quickly and at scale to narrow down on potentially interesting hosts during an IR. A great demonstration of this approach can be seen in the Video Live Incident Response with Velociraptor where Eric Capuano uses the Hayabusa tool deployed via Velociraptor to quickly identify the attack techniques evident on the endpoint.
Previously we could only apply Sigma rules in Velociraptor by bundling the Hayabusa tool, which presents a curated set of Sigma rules but runs locally. In this release Sigma matching is done natively in Velociraptor and therefore the Velociraptor Sigma project simply curates the same rules that Hayabusa curates but does not require the Hayabusa binary itself.
You can read the full Sigma In Velociraptor blog post that describes this feature in great detail, but here I will quickly show how it can be used to great effect.
First I will import the set of curated Sigma rules from the Velociraptor Sigma project by collecting the Server.Import.CuratedSigma server artifact.
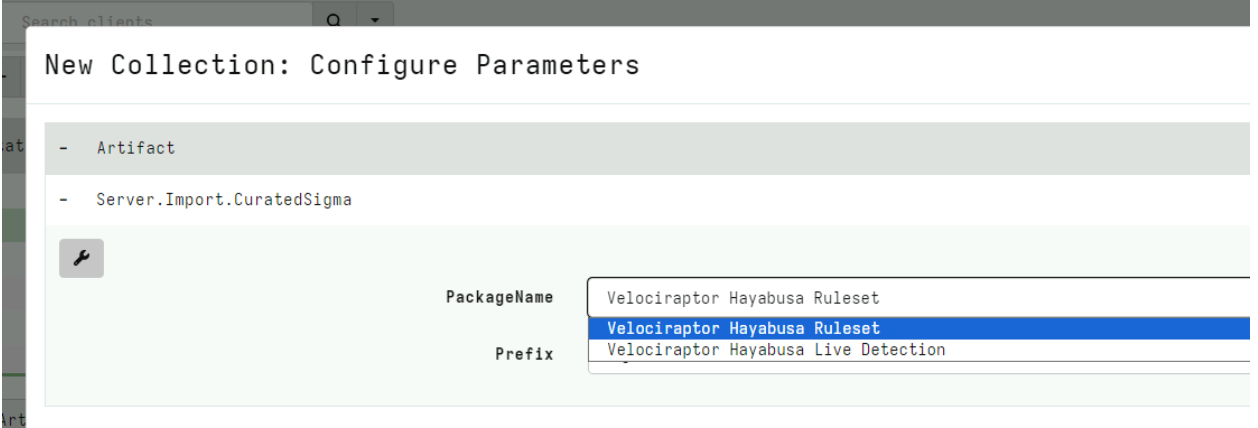
This will import a new artifact to my system with up to date Sigma rules, divided into different Status, Rule Level etc. For this example I will select the Stable rules at a Critical Level.
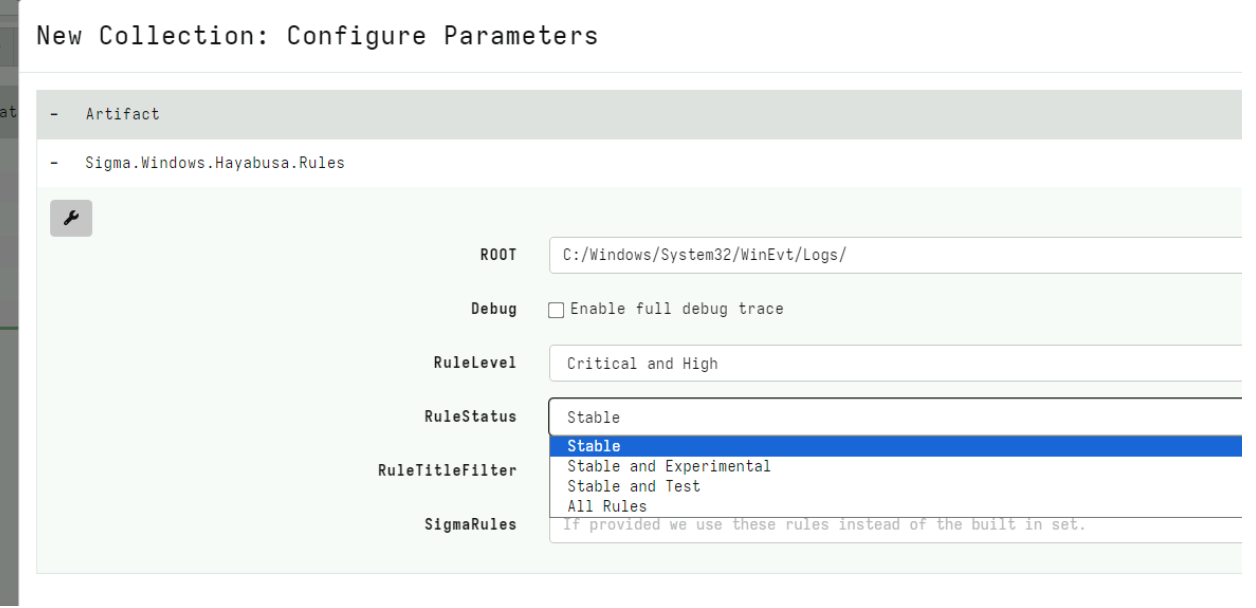
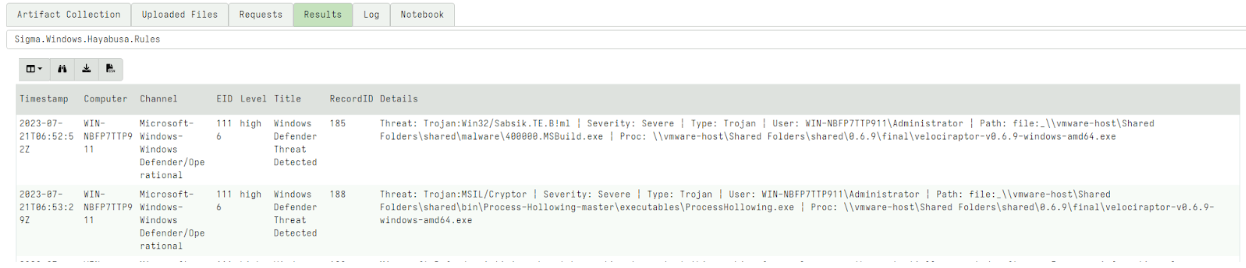
After launching the collection, the artifact will return all the matching rules and their relevant events. This is a quick artifact taking less than a minute on my test system. I immediately see interesting hits.
Using Sigma rules for live monitoring
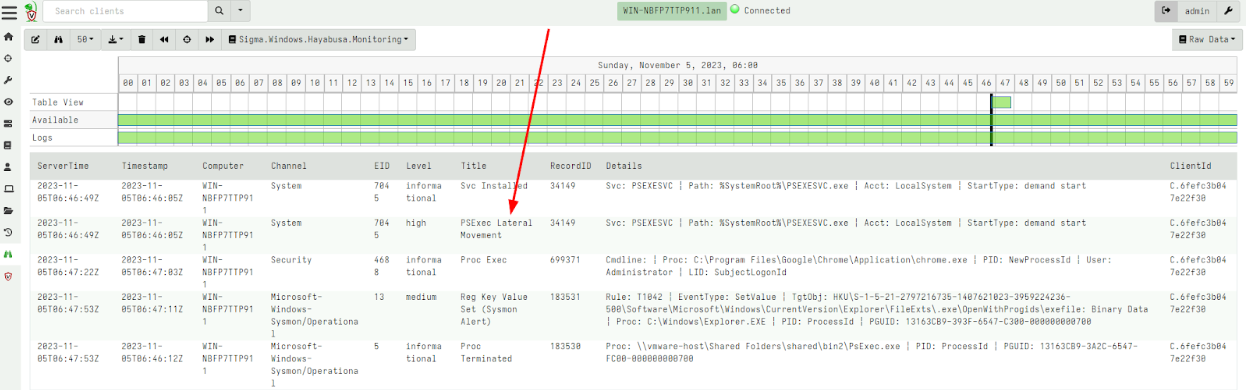
Sigma rules can be used on more than just log files. The Velociraptor Sigma project also provides monitoring rules that can be used on live systems for real time monitoring.
The Velociraptor Hayabusa Live Detection option in the Curated import artifact will import an event monitoring version of the same curated Sigma rules. After adding the rule to the client’s monitoring rules with the GUI, I can receive interesting events for matching rules:
Other Improvements
SSH/SCP accessor
Velociraptor normally runs on the endpoint and can directly collect evidence from the endpoint. However, many devices on the network can not install an endpoint agent – either because the operating system is not supported (for example embedded versions of Linux) or due to policy.
When we need to investigate such systems we often can only access them by Secure Shell (SSH). In the 0.7.1 release, Velociraptor has an ssh accessor which allows all plugins that normally use the filesystem to transparently use SSH instead.
For example, consider the glob() plugin which searches for files.
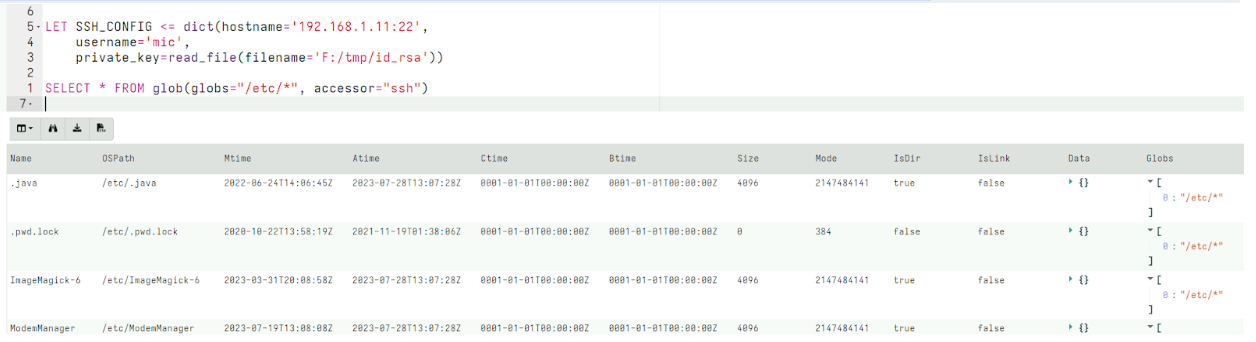
We can specify that the glob() use the ssh accessor to access the remote system. By setting the SSH_CONFIG VQL variable, the accessor is able to use the locally stored private key to be able to authenticate with the remote system to access remote files.
We can combine this new accessor with the remapping feature to reconfigure the VQL engine to substitute the auto accessor with the ssh accessor when any plugin attempts to access files. This allows us to transparently use the same artifacts that would access files locally, but this time transparently will access these files over SSH:
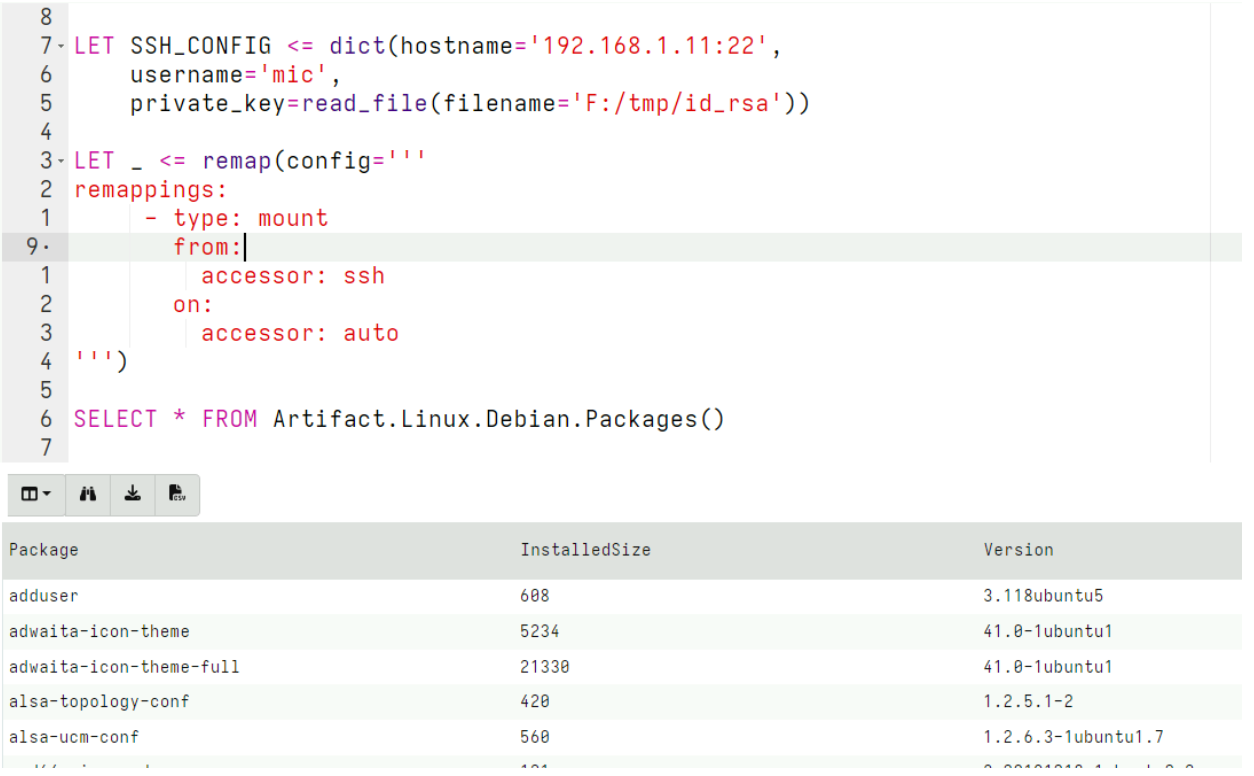
This example shows how to use the SSH accessor to investigate a debian system and collect the Linux.Debian.Packages artifact from it over SSH.
Distributed notebook processing
While Velociraptor is very efficient and fast, and can support a large number of endpoints connected to the server, many users told us that on busy servers, running notebook queries can affect server performance. This is because a notebook query can be quite intense (e.g. Sorting or Grouping a large data set) and in the default configuration the same server is collecting data from clients, performing hunts, and also running the notebook queries.
This release allows notebook processors to be run in another process. In Multi-Frontend configurations (also called Master/Minion configuration), the Minion nodes will now offer to perform notebook queries away from the master node. This allows this sudden workload to be distributed to other nodes in the cluster and improve server and GUI performance.
ETW Multiplexing
Previous support for Event Tracing For Windows (ETW) was rudimentary. Each query that called the watch_etw() plugin to receive the event stream from a particular provider created a new ETW session. Since the total number of ETW sessions on the system is limited to 64, this used precious resources.
In 0.7.1 the ETW subsystem was overhauled with the ability to multiplex many ETW watchers on top of the same session. The ETW sessions are created and destroyed on demand. This allows us to more efficiently track many more ETW providers with minimal impact on the system.
Additionally the etw_sessions() plugin can show statistics for all sessions currently running including the number of dropped events.
Artifacts can be hidden in the GUI
Velociraptor comes with a large number of built in artifacts. This can be confusing for new users and admins may want to hide artifacts in the GUI.
You can now hide an artifact from the GUI using the artifact_set_metadata() VQL function. For example the following query will hide all artifacts which do not have Linux in their name.
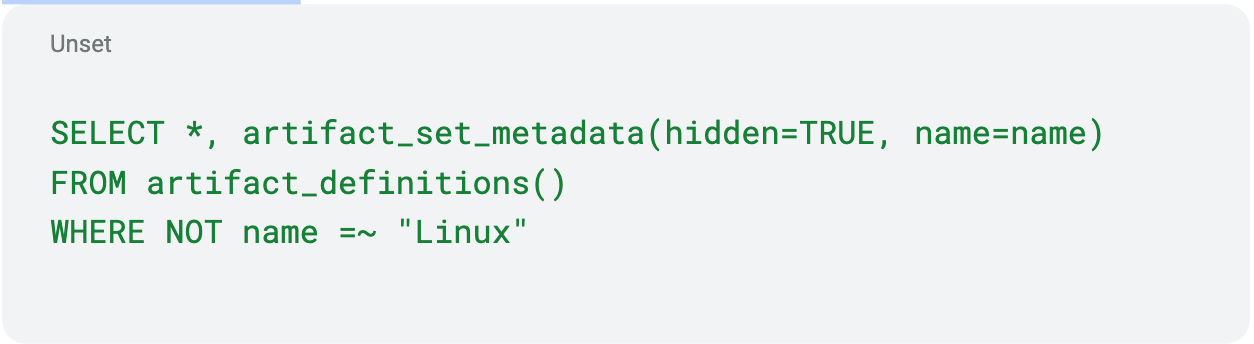
Only Linux related artifacts will now be visible in the GUI.
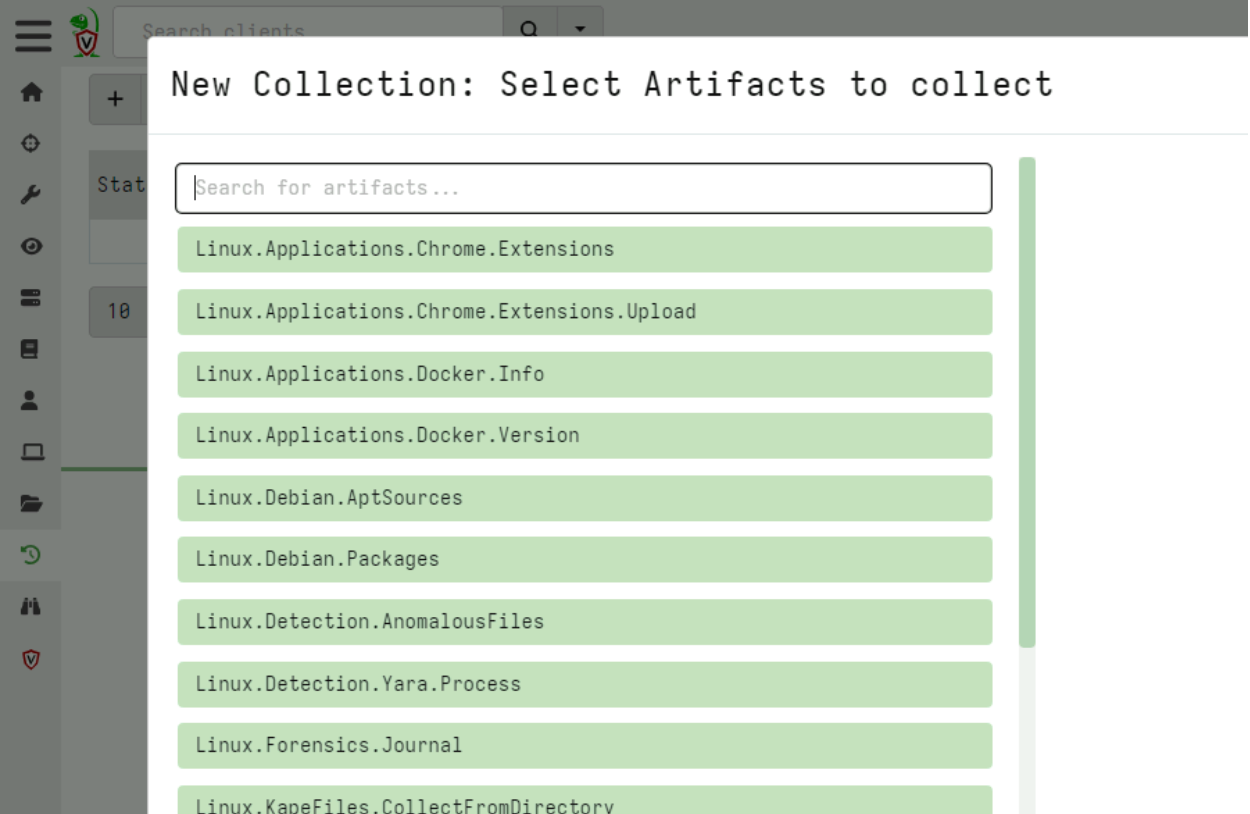
Local encrypted storage for clients
It is sometimes useful to write data locally on endpoints instead of transferring the data to the server. For example, if the client is not connected to the internet for long periods it is useful to write data locally. Also useful is to write data in case we want to recover it later during an investigation.
The downside of writing data locally on the endpoints is that this data may be accessed if the endpoint is later compromised. If the data contains sensitive information this can be used by an attacker. This is also primarily the reason that Velociraptor does not write a log file on the endpoint. Unfortunately this makes it difficult to debug issues.
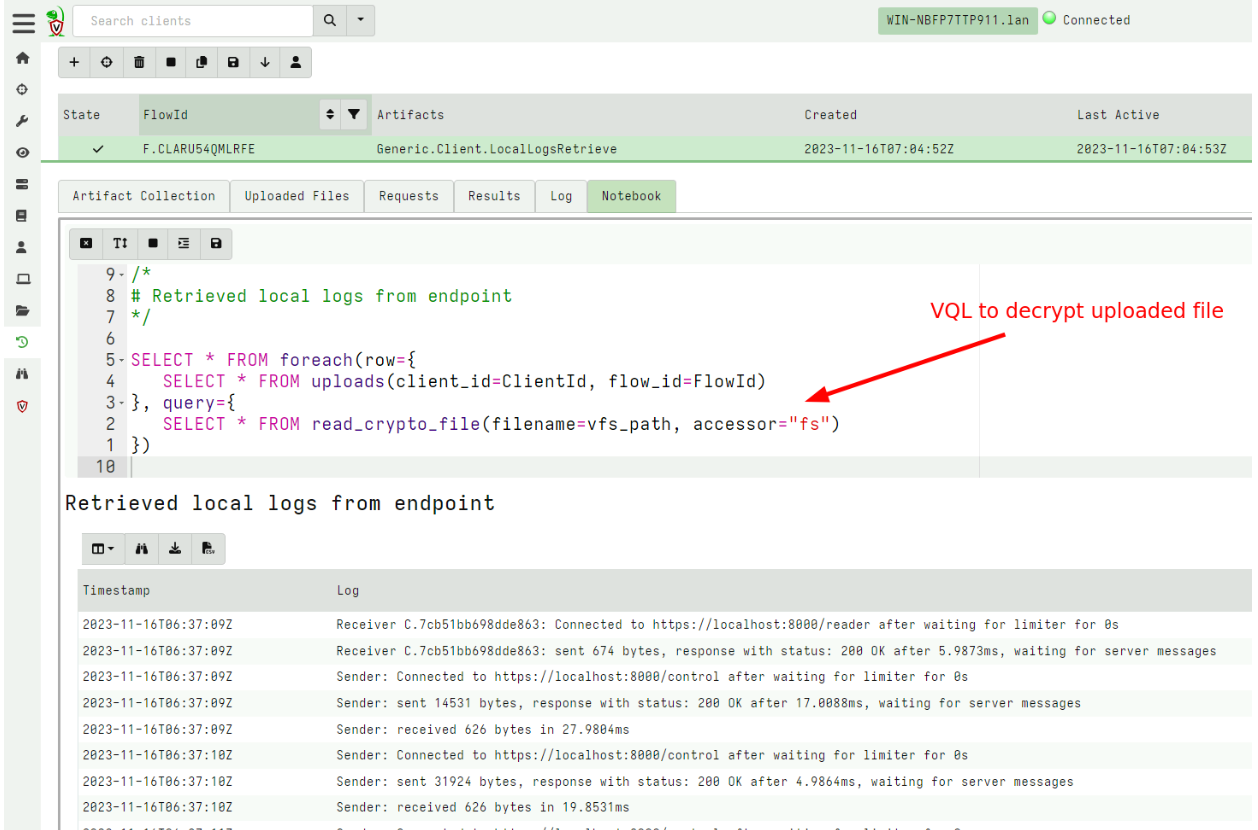
The 0.7.1 release introduces a secure local log file format. This allows the Velociraptor client to write to the local disk in a secure way. Once written the data can only be decrypted by the server.
While any data can be written to the encrypted local file, the Generic.Client.LocalLogs artifact allows Velociraptor client logs to be written at runtime.
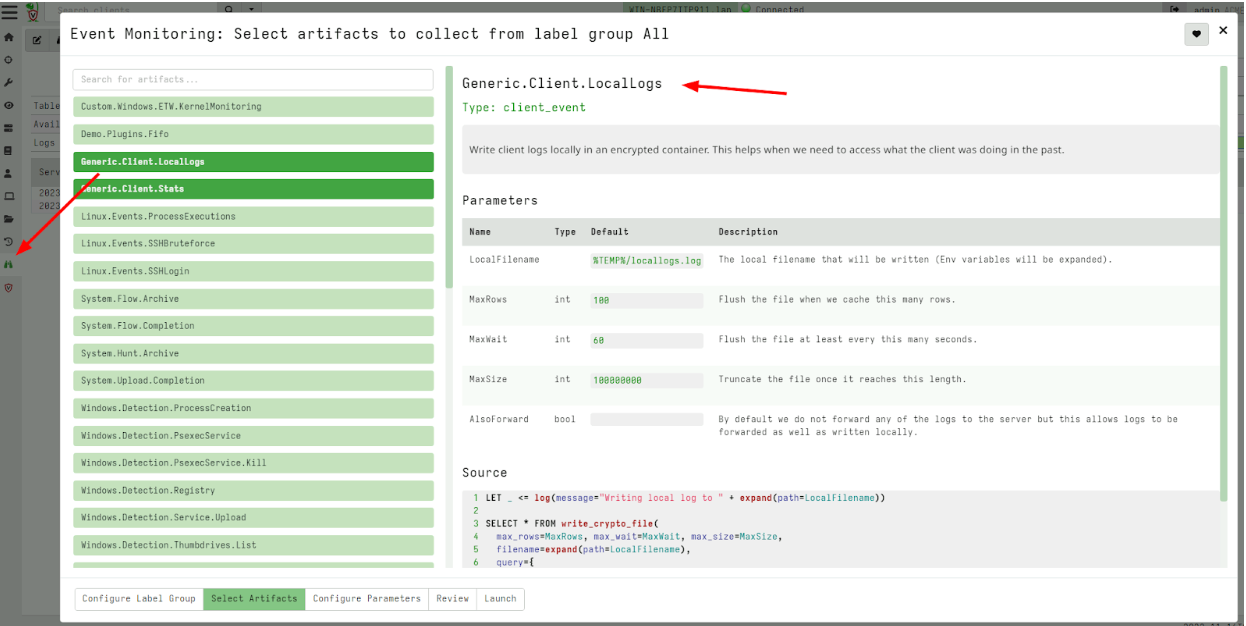
To read these locally stored logs I can fetch them using the Generic.Client.LocalLogsRetrieve artifact to retrieve the encrypted local file. The file is encrypted using the server’s public key and can only be decrypted on the server.
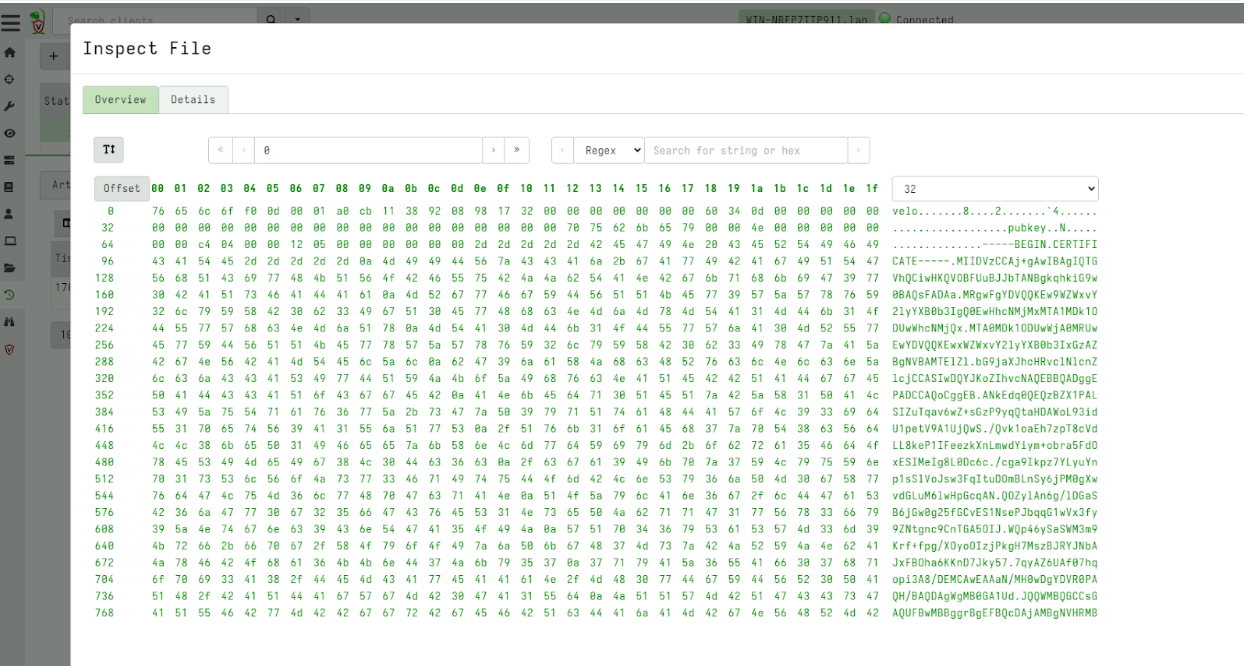
Once on the server, I can decrypt the file using the collection’s notebook which automatically decrypts the uploaded file.
Conclusions
There are many more new features and bug fixes in the 0.7.1 release. If you’re interested in any of these new features, we welcome you to take Velociraptor for a spin by downloading it from our release page. It’s available for free on GitHub under an open-source license.
As always, please file bugs on the GitHub issue tracker or submit questions to our mailing list by emailing [email protected]. You can also chat with us directly on our Discord server.
Learn more about Velociraptor by visiting any of our web and social media channels below:
Raspberry Pi 5 w/ Home Assistant – Worth the Upgrade?
Post Syndicated from digiblurDIY original https://www.youtube.com/watch?v=kaVND-M9pkA
Gentoo in binary form
Post Syndicated from corbet original https://lwn.net/Articles/956366/
Gentoo Linux is the prototypical source-based distribution, but there is
now a
binary installation option available as well.
To speed up working with slow hardware and for overall convenience,
we’re now also offering binary packages for download and direct
installation! For most architectures, this is limited to the core
system and weekly updates – not so for amd64 and arm64
however. There we’ve got a stunning >20 GByte of packages on our
mirrors, from LibreOffice to KDE Plasma and from Gnome to Docker.
LGR – The Sims 4 For Rent Review
Post Syndicated from LGR original https://www.youtube.com/watch?v=XIS8nXYaEpM
The "Great Ivy League Nude Posture Photos Scandal"
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/watch?v=njE7y_oOHi4
AI Is Scarily Good at Guessing the Location of Random Photos
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/12/ai-is-scarily-good-at-guessing-the-location-of-random-photos.html
Wow:
To test PIGEON’s performance, I gave it five personal photos from a trip I took across America years ago, none of which have been published online. Some photos were snapped in cities, but a few were taken in places nowhere near roads or other easily recognizable landmarks.
That didn’t seem to matter much.
It guessed a campsite in Yellowstone to within around 35 miles of the actual location. The program placed another photo, taken on a street in San Francisco, to within a few city blocks.
Not every photo was an easy match: The program mistakenly linked one photo taken on the front range of Wyoming to a spot along the front range of Colorado, more than a hundred miles away. And it guessed that a picture of the Snake River Canyon in Idaho was of the Kawarau Gorge in New Zealand (in fairness, the two landscapes look remarkably similar).
This kind of thing will likely get better. And even if it is not perfect, it has some pretty profound privacy implications (but so did geolocation in the EXIF data that accompanies digital photos).
Friday Squid Blogging: Sqids
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2023/12/friday-squid-blogging-sqids.html
They’re short unique strings:
Sqids (pronounced “squids”) is an open-source library that lets you generate YouTube-looking IDs from numbers. These IDs are short, can be generated from a custom alphabet and are guaranteed to be collision-free.
I haven’t dug into the details enough to know how they can be guaranteed to be collision-free.
As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.
Read my blog posting guidelines here.
„Целият граждански сектор е под прицел.“ Разговор с Георги Богданов
Post Syndicated from Светла Енчева original https://www.toest.bg/tseliyat-grazhdanski-sektor-e-pod-pritsel-razgovor-s-georgi-bogdanov/

Гражданският сектор в България върши незаменима работа в сфери, в които държавата отсъства. В същото време той е обект на множество очернящи кампании. След активното мероприятие срещу Конвенцията на Съвета на Европа за превенция и борба с насилието над жени и домашното насилие, по-известна като Истанбулската конвенция, примката около неправителствените организации се затегна още повече. Натискът върху тях и представянето им в негативна светлина обаче не са от вчера. Думата „соросоиди“ (по името на основателя на Фондация „Отворено общество“ Джордж Сорос), която е негативно обобщаващо название на представителите на неправителствените организации, циркулира в публичното пространство от поне двайсетина години.
За проблемите, перспективите и потенциала за справяне на гражданския сектор разговаряме с Георги Богданов, който е изпълнителен директор на Националната мрежа за децата (НМД). Тя обединява повече от 130 организации и активисти. В основата ѝ стои убеждението, че детето е човешко същество и има права. „Това е толкова просто, но и много сложно за възприемане“, казва Богданов и пояснява привидното противоречие: „У нас се счита, че детето е малко същество, което трябва да бъде послушно, благодарно и да си знае задълженията. Но животът не е такъв. Ако караме децата ни да слушат и да възхваляват възрастните, ние възпитаваме хора, които в бъдеще няма да са способни да се справят с проблемите си.“
Георги Богданов, както и представителите на 120 граждански организации бяха част от предаването „Властта на гражданите“, което се излъчваше по „Дарик радио“ през последните четири години и се реализираше в рамките на проекта „Какво можем заедно“.
Невидимите трудности зад видимите успехи
В равносметката на НМД за 2023 г. присъстват над 30 значителни постижения. Но Мрежата има както успехи, така и неуспехи, смята Георги Богданов. Според него един от проблемите пред гражданския сектор е, че в България трудно се разбира естеството на застъпническата работа. „Зад една промяна в законодателството се работи с години, като например последните промени от декември 2023 г. в Семейния кодекс.“ Става дума за поправката, даваща възможност на осиновените хора по-лесно да открият биологичните си родители. Tази промяна, по думите на вносителите, засяга над два милиона души – не само осиновените, осиновителите и биологичните родители, а и техните близки и роднини.
Друга победа е извоювана за по-кратко време, но с не по-малко усилия. Преди две години, когато пандемията от COVID-19 започва да отшумява и противоепидемичните мерки се разхлабват, заведенията и магазините се отварят, но не и училищата. „Тоест децата можеха да се шляят в моловете и да ходят на ресторант, но не и в училище“, припомня Богданов. Тогава от НМД са поканени на пресконференция от тогавашните министри на здравеопазването и на образованието, които нямат обща позиция дали учениците да се върнат в класните стаи. Въпреки че преди това от организацията са провели десетки разговори с двамата поотделно, убеждавайки ги, че България трябва да постъпи като другите европейски страни – да осигури бързи тестове и децата да тръгнат на училище.
„Пресконференцията закъсня с около половин час, но там буквално си крещяхме“, разказва директорът на НМД. Накрая спорещите страни стигат до консенсус и заедно отиват на пресконференцията, където обявяват, че ще се закупят експресно бързи тестове. „И от следващата седмица в училище влязоха над 520 000 деца.“
Причини за кампаниите срещу гражданския сектор
НМД е сред основните обекти на кампаниите срещу НПО сектора, а самият Георги Богданов е „герой“ на не едно и две очернящи мемета. Хейта по свой адрес възприема философски: „Аз съм един от лидерите на най-голямата гражданска организация в страната и е естествено да съм най-атакуван от пропагандата.“ Това не означава, че се примирява с клеветите по свой адрес – напротив, води дела срещу шестима души и една телевизия. Някои от тях печели, други губи. Загубите отдава на обстоятелството, че клеветите в интернет са „изключителна новост“ за българските съдилища – въпреки множеството експертизи, които се извършват в тази област. „Съдебната ни практика е доста ограничена в тази посока, но аз съм въоръжен с търпение и знам, че битката ще е дълга.“
Според изпълнителния директор на НМД обаче по-притеснителното е, че „целият граждански сектор е под прицел, защото той е част от демократичното развитие на страната“. Това превръща НПО-тата в мишена на крайнодесни политически формации и фундаменталистки религиозни организации.
Редица изследвания и журналистически материали показват, че основните ядра на тези идеологически кампании идват от две основни гнезда. Едното е Кремъл, а другото – крайни религиозни организации, базирани в САЩ и Европа. Няма как тези атаки да не достигат до нас, които сме пазители на демокрацията и на съвременните достижения на научната и прогресивна общност.
Той вярва в плурализма и затова не смята, че е лошо, че едни от най-изявените врагове на НПО-тата също са регистрирани като НПО-та. Изпитва обаче нетърпимост към налагането на страхове в обществото, прибягването до лъжи и „изкривени истини“, създаването на „обществени страшилища“ като „джендъра“, „соросоидите“ или „норвежците“:
Пропагандата и дезинформацията налагат тези глупости, за да насаждат страх, омраза и ненавист към други хора от обществото. Тези НПО-та си имат своите методи на работа. Те са против Стратегията, против „джендъра“, против ваксината, против маската… И като ги запиташ: „Вие за какво сте в крайна сметка, какво искате?“, те нямат ясен отговор.
Друга причина за очернянето на сектора е, че той се застъпва за прозрачност и спира корумпирани или „глупави“, по думите на Богданов, сделки на държавно равнище. Той дава пример с изоставения строеж в двора на Александровска болница, „където щяха да се изхарчат най-малко 100 млн. лв., предназначени за детската болница“.
Последствия от поредицата кампании срещу НПО сектора
Кампаниите срещу Истанбулската конвенция, Стратегията за детето и Закона за социалните услуги се насложиха една върху друга и по този начин увеличиха ефекта си. „Беше много тежък период за НМД и за нас като секретариат“, признава Георги Богданов, но в същото време вижда и позитивен ефект – днес секторът е много по-подготвен от преди. Неуспехите в началото според него се дължат на това, че нито гражданският сектор, нито журналистите са били подготвени за тези кампании, „а политиците бяха като втрещени и не знаеха какво се случва и откъде идва това“.
Още при първата истерия срещу „джендъра“ Богданов е наясно, че следващите в списъка са детските организации и изобщо правата на децата. „Само след по-малко от година започна атаката срещу Стратегията за детето. Слабият кабинет на Борисов по социалните въпроси не успя да удържи атаката срещу Стратегията за детето, а коалиционният партньор ВМРО се възползва от това. Днес ВМРО ги няма на политическата сцена, но ние вече четвърта година нямаме Стратегия за детето, въпреки че по закон трябва да имаме.“ Що се отнася до Закона за социалните услуги, подложен на атака „от същите тези пропагандни НПО-та“, той още не може да заработи пълноценно, макар да е „един от най-модерните закони в страната ни“.
За НМД няма пряко негативно последствие от пропагандните кампании, смята директорът ѝ, но негативите са за децата и семействата в България – до степен родители да извеждат децата си от училище, за да не ги откраднат. Докато някои хора „продължават да се страхуват някой да не дойде да им вземе децата и да ги занесат към Норвегия или пък да не вземат да им сменят пола в училище, докато са в клас“, се губи ценно време. През което биха могли да се направят далеч по-смислени неща – „да се решават проблеми с бедността, изоставянето, биенето и малтретирането на деца, продължаващото ниско качество на образованието ни, липсата на медицински храни за деца и възрастни и пр.“
Последиците от кампаниите са и цивилизационни. Те отдалечават обществото от достиженията на съвременния свят. „Някои хора у нас са загубили вяра в иновациите, в научните открития на човечеството, знанието и достигнатите общочовешки ценности. Днес се вярва, че ако едно човешко същество има права, то на друго са му отнети, а е доста по-просто. Всеки човек се ражда с права, защото е човешко същество – и точка. Никой на никого не взема нещо. Ако някой човек има права, той ги има, защото просто е човек като всеки друг“, казва Богданов и призовава „да сме много по-активни граждани, да отстояваме правата си, да не се отказваме от тях и да сме политически грамотни“.
Умишленото обезкървяване на гражданския сектор
Гражданският сектор в България е слаб, защото не намира подкрепа и няма среда, в която да се развива, смята Георги Богданов. Според него е необходима държавна регулация, подкрепяща дарителството и доброволчеството, както и намалени данъчни ставки за тези дейности, но това не се случва:
Ами ние повече от 15 години един Закон за доброволчеството не можем да приемем, който да дава право доброволец да бъде командирован, да има дневни и пр. За промени в данъчните закони да сте чули да се прави нещо за насърчаване на дарителството? Аз лично не съм.
Усилия за намаляване на местните данъци и такси също липсват, но пък „имаме дневни центрове за деца с увреждания, които плащат по 6000 лв. годишна такса смет – колкото един мол.“ Към това се прибавя недостигът на финансиращи програми, а европейските средства се разпределят основно между публичните институции.
„Така този сектор е оставен обезкървен и на колене. И ми кажете – как той би се справил с една очерняща кампания, която е добре финансирана, добре организирана и подготвена да води битка срещу граждански организации, които се грижат за бити жени и деца, за хора с увреждания или за пострадали от онлайн тормоз?“, пита реторично Богданов, а заключението му звучи мрачно:
Много организации се закриха в страната ни, гражданските активисти са уморени, а като цяло обществото е апатично. И това е целта на политическата класа. Няма грижа за гражданското общество в България.
Проблемът с „Българската Коледа“ като огледало на проблемите на гражданския сектор
Според Георги Богданов положението в България е „доста сбъркано“. Той дава пример с президентската кампания „Българската Коледа“, в рамките на която се събират дарения за финансиране на болнични отделения, деца с увреждания и т.н. Тази кампания е „сбъркана“, тъй като работата на държавата е да се погрижи за тези неща, вместо да кара гражданите си да правят дарения за дейности, които следва да се извършват с парите от техните данъци.
„Очаквам един ден да дойде моят президент на България, който ще сложи край на „Българската Коледа“, размечтава се Богданов. Той е съгласен и с междинен вариант – този бъдещ президент да продължи инициативата, но да я трансформира така, че „да има смисъл за развитието на гражданския сектор, благотворителността или друга кауза, която да развива обществото. А не да даваме пари за болнично отделение. Защото пари за здравеопазване има, но те не се харчат ефективно и целесъобразно“.
Политиците и държавниците следва да осъзнаят, че трябва да подкрепят инициативността и гражданското действие, да дадат възможност на сектора да се развива, вместо да правят псевдокампании, смята директорът на НМД. А това не може да стане без по-добра правна рамка и по-широк достъп до европейско финансиране – гражданските организации не са търговски дружества и се нуждаят от финансиране, защото не работят на печалба.
Само ако са изпълнени тези условия, „гражданският сектор ще изгради своя авторитет и ще има възможност да работи за граждански каузи много по-свободно и целеустремено“.
Проектът „Какво можем заедно“ се изпълнява от Фондация „Дарик“, Фондация „Четиридесет и две“ и Фондация ПАЦЕП с финансова подкрепа, предоставена от Фонд „Активни граждани България“ по линия на Финансовия механизъм на ЕИП. Основната цел на проекта „Какво можем заедно“ е обществеността да се запознае с хората, които работят в граждански организации, да разбере какво стои зад усилията им, каква е тяхната мотивация и какви са успехите им.
Тази статия е публикувана с финансовата подкрепа на Фондация „Дарик“, Фондация „Четиридесет и две“ и Фондация ПАЦЕП в рамките на проекта „Какво можем заедно“.

ASUS S14NA-U12 AMD EPYC 8004 Siena Motherboard Review
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/asus-s14na-u12-amd-epyc-8004-siena-motherboard-review-broadcom/
In our ASUS S14NA-U12 review, we see how this AMD EPYC 8004 “Siena” motherboard manages to expose the platform’s capabilities and add 25GbE
The post ASUS S14NA-U12 AMD EPYC 8004 Siena Motherboard Review appeared first on ServeTheHome.
Comic for 2023.12.29 – But Babe…
Post Syndicated from Explosm.net original https://explosm.net/comics/but-babe
New Cyanide and Happiness Comic
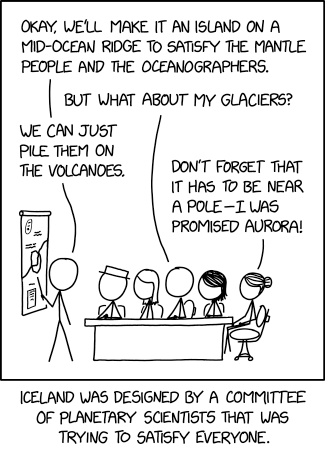
Iceland
Post Syndicated from xkcd.com original https://xkcd.com/2874/
Rust 1.75.0 released
Post Syndicated from corbet original https://lwn.net/Articles/956303/
Version
1.75.0 of the Rust language has been released. Notable changes include
“async
fn and -> impl Trait in traits“, a pointer byte-offset
API, some compiler performance improvements, and a number of stabilized APIs.
Using Amazon GuardDuty ECS runtime monitoring with Fargate and Amazon EC2
Post Syndicated from Luke Notley original https://aws.amazon.com/blogs/security/using-amazon-guardduty-ecs-runtime-monitoring-with-fargate-and-amazon-ec2/
Containerization technologies such as Docker and orchestration solutions such as Amazon Elastic Container Service (Amazon ECS) are popular with customers due to their portability and scalability advantages. Container runtime monitoring is essential for customers to monitor the health, performance, and security of containers. AWS services such as Amazon GuardDuty, Amazon Inspector, and AWS Security Hub play a crucial role in enhancing container security by providing threat detection, vulnerability assessment, centralized security management, and native Amazon Web Services (AWS) container runtime monitoring.
GuardDuty is a threat detection service that continuously monitors your AWS accounts and workloads for malicious activity and delivers detailed security findings for visibility and remediation. GuardDuty analyzes tens of billions of events per minute across multiple AWS data sources and provides runtime monitoring using a GuardDuty security agent for Amazon Elastic Kubernetes Service (Amazon EKS), Amazon ECS and Amazon Elastic Compute Cloud (Amazon EC2) workloads. Findings are available in the GuardDuty console, and by using APIs, a copy of every GuardDuty finding is sent to Amazon EventBridge so that you can incorporate these findings into your operational workflows. GuardDuty findings are also sent to Security Hub helping you to aggregate and corelate GuardDuty findings across accounts and AWS Regions in addition to findings from other security services.
We recently announced the general availability of GuardDuty Runtime Monitoring for Amazon ECS and the public preview of GuardDuty Runtime Monitoring for Amazon EC2 to detect runtime threats from over 30 security findings to protect your AWS Fargate or Amazon EC2 ECS clusters.
In this blog post, we provide an overview of the AWS Shared Responsibility Model and how it’s related to securing your container workloads running on AWS. We look at the steps to configure and use the new GuardDuty Runtime Monitoring for ECS, EC2, and EKS features. If you’re already using GuardDuty EKS Runtime Monitoring, this post provides the steps to migrate to GuardDuty Runtime Monitoring.
AWS Shared Responsibility Model and containers
Understanding the AWS Shared Responsibility Model is important in relation to Amazon ECS workloads. For Amazon ECS, AWS is responsible for the ECS control plane and the underlying infrastructure data plane. When using Amazon ECS on an EC2 instance, you have a greater share of security responsibilities compared to using ECS on Fargate. Specifically, you’re responsible for overseeing the ECS agent and worker node configuration on the EC2 instances.
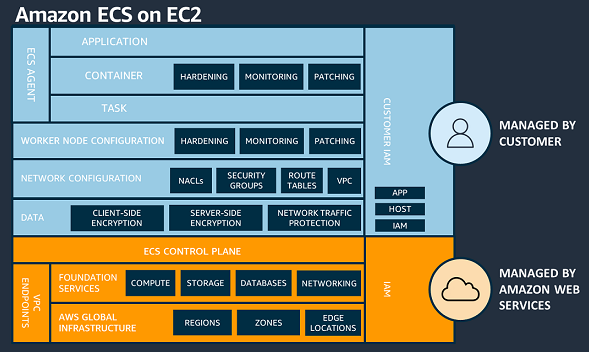
Figure 1: AWS Shared Responsibility Model – Amazon ECS on EC2
In Fargate, each task operates within its dedicated virtual machine (VM), and there’s no sharing of the operating system or kernel resources between tasks. With Fargate, AWS is responsible for the security of the underlying instance in the cloud and the runtime used to run your tasks.
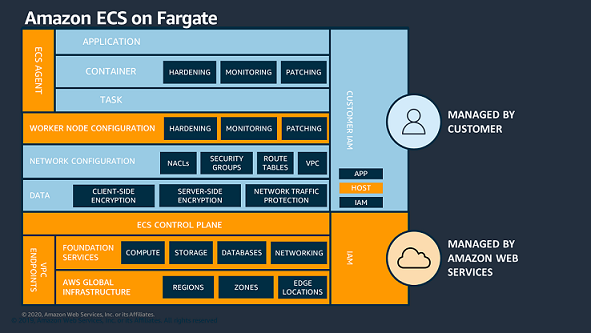
Figure 2: AWS Shared Responsibility Model – Amazon ECS on Fargate
When deploying container runtime images, your responsibilities include configuring applications, ensuring container security, and applying best practices for task runtime security. These best practices help to limit adversaries from expanding their influence beyond the confines of the local container process.
Amazon GuardDuty Runtime Monitoring consolidation
With the new feature launch, EKS Runtime Monitoring has now been consolidated into GuardDuty Runtime Monitoring. With this consolidation, you can manage the configuration for your AWS accounts one time instead of having to manage the Runtime Monitoring configuration separately for each resource type (EC2 instance, ECS cluster, or EKS cluster). A view of each Region is provided so you can enable Runtime Monitoring and manage GuardDuty security agents across each resource type because they now share a common value of either enabled or disabled.
Note: The GuardDuty security agent still must be configured for each supported resource type.
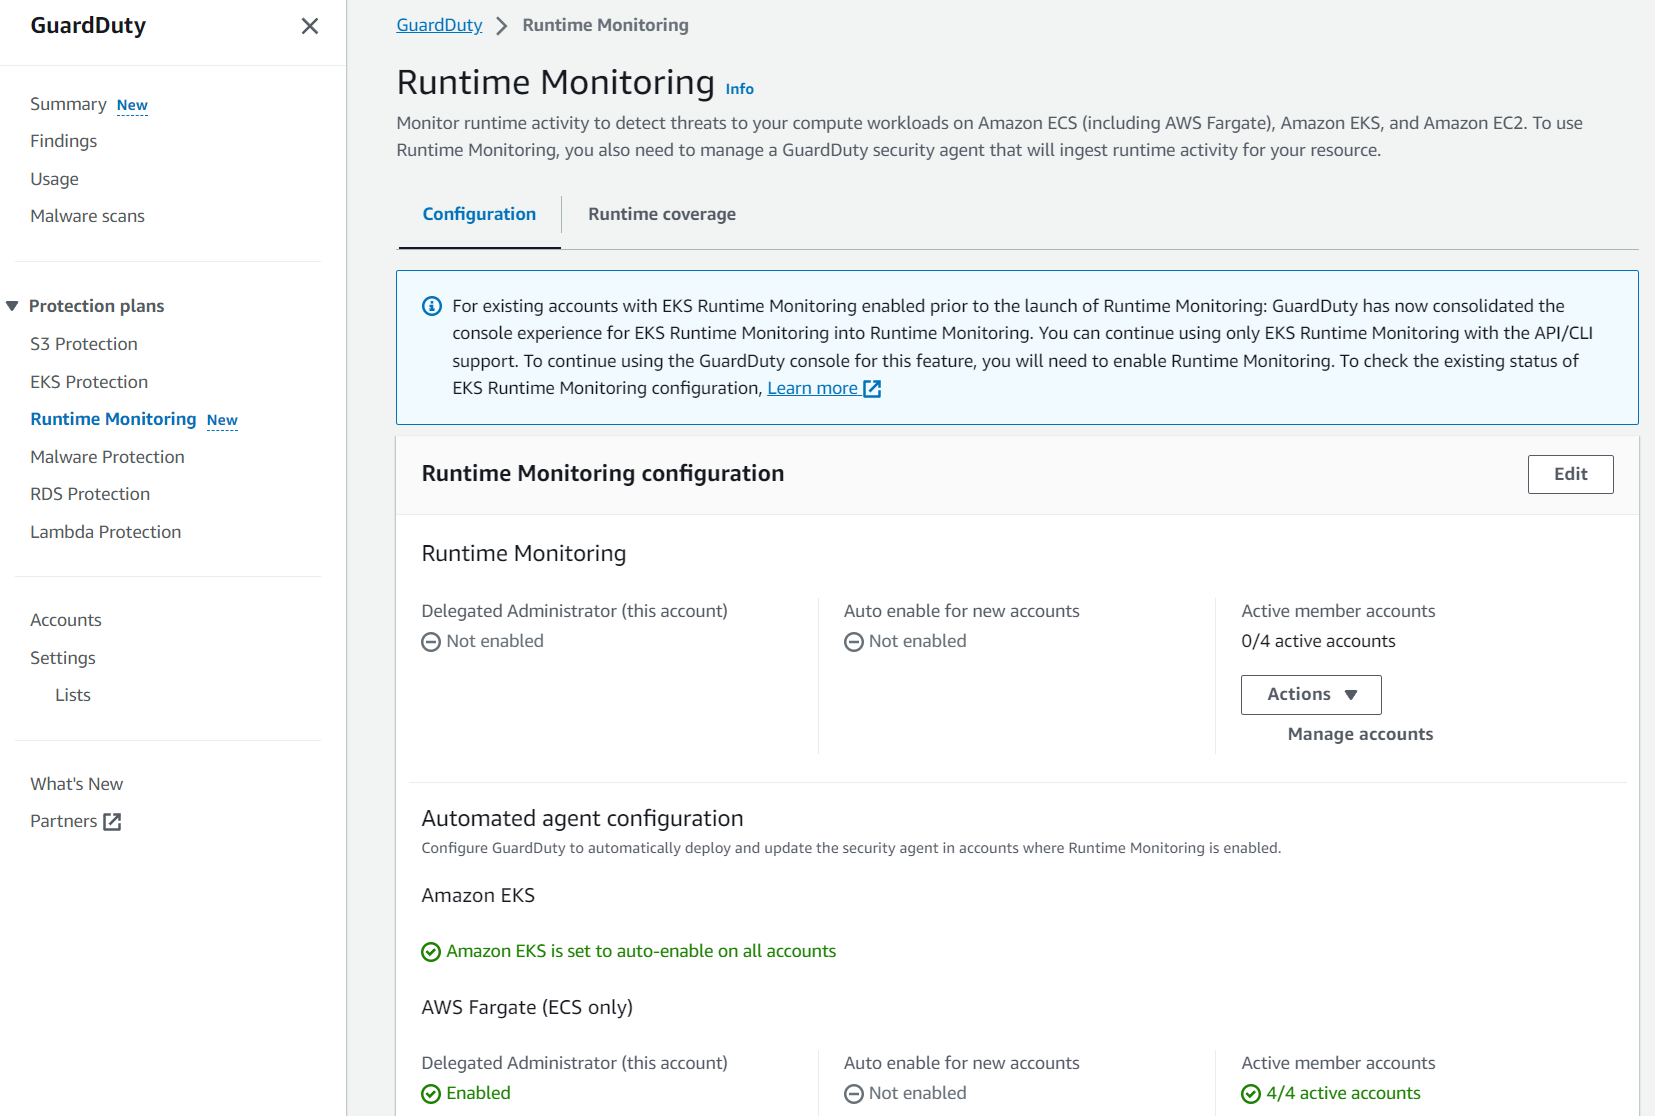
Figure 3: GuardDuty Runtime Monitoring overview
In the following sections, we walk you through how to enable GuardDuty Runtime Monitoring and how you can reconfigure your existing EKS Runtime Monitoring deployment. We also cover how you can enable monitoring for ECS Fargate and EC2 resource types.
If you were using EKS Runtime Monitoring prior to this feature release, you will notice some configuration options in the updated AWS Management Console for GuardDuty. It’s recommended that you enable Runtime Monitoring for each AWS account; to do this, follow these steps:
- In the GuardDuty console, in the navigation pane under Protection plans, select Runtime Monitoring.
- Select the Configuration tab and then choose Edit.
- Under Runtime Monitoring, select Enable for all accounts.
- Under Automated agent configuration – Amazon EKS, ensure Enable for all accounts is selected.
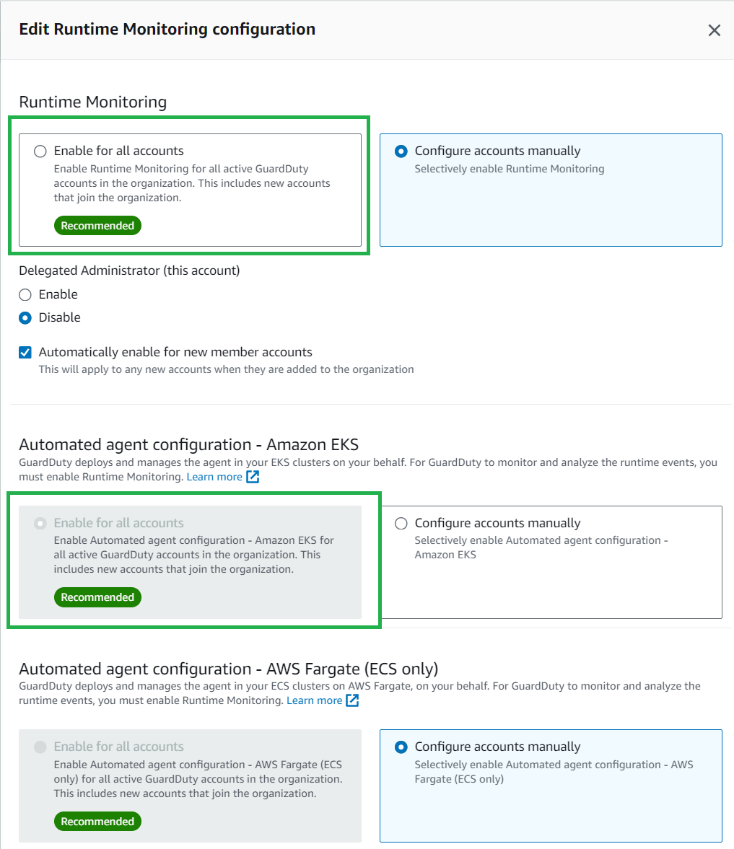
Figure 4: Edit GuardDuty Runtime Monitoring configuration
If you want to continue using EKS Runtime Monitoring without enabling GuardDuty ECS Runtime Monitoring or if the Runtime Monitoring protection plan isn’t yet available in your Region, you can configure EKS Runtime Monitoring using the AWS Command Line Interface (AWS CLI) or API. For more information on this migration, see Migrating from EKS Runtime Monitoring to GuardDuty Runtime Monitoring.
Amazon GuardDuty ECS Runtime Monitoring for Fargate
For ECS using a Fargate capacity provider, GuardDuty deploys the security agent as a sidecar container alongside the essential task container. This doesn’t require you to make changes to the deployment of your Fargate tasks and verifies that new tasks will have GuardDuty Runtime Monitoring. If the GuardDuty security agent sidecar container is unable to launch in a healthy state, the ECS Fargate task will not be prevented from running.
When using GuardDuty ECS Runtime Monitoring for Fargate, you can install the agent on Amazon ECS Fargate clusters within an AWS account or only on selected clusters. In the following sections, we show you how to enable the service and provision the agents.
Prerequisites
If you haven’t activated GuardDuty, learn more about the free trial and pricing and follow the steps in Getting started with GuardDuty to set up the service and start monitoring your account. Alternatively, you can activate GuardDuty by using the AWS CLI. The minimum Fargate environment version and container operating systems supported can be found in the Prerequisites for AWS Fargate (Amazon ECS only) support. The AWS Identity and Access Management (IAM) role used for running an Amazon ECS task must be provided with access to Amazon ECR with the appropriate permissions to download the GuardDuty sidecar container. To learn more about Amazon ECR repositories that host the GuardDuty agent for AWS Fargate, see Repository for GuardDuty agent on AWS Fargate (Amazon ECS only).
Enable Fargate Runtime Monitoring
To enable GuardDuty Runtime Monitoring for ECS Fargate, follow these steps:
- In the GuardDuty console, in the navigation pane under Protection plans, select Runtime Monitoring.
- Select the Configuration tab and then in the AWS Fargate (ECS only) section, choose Enable.
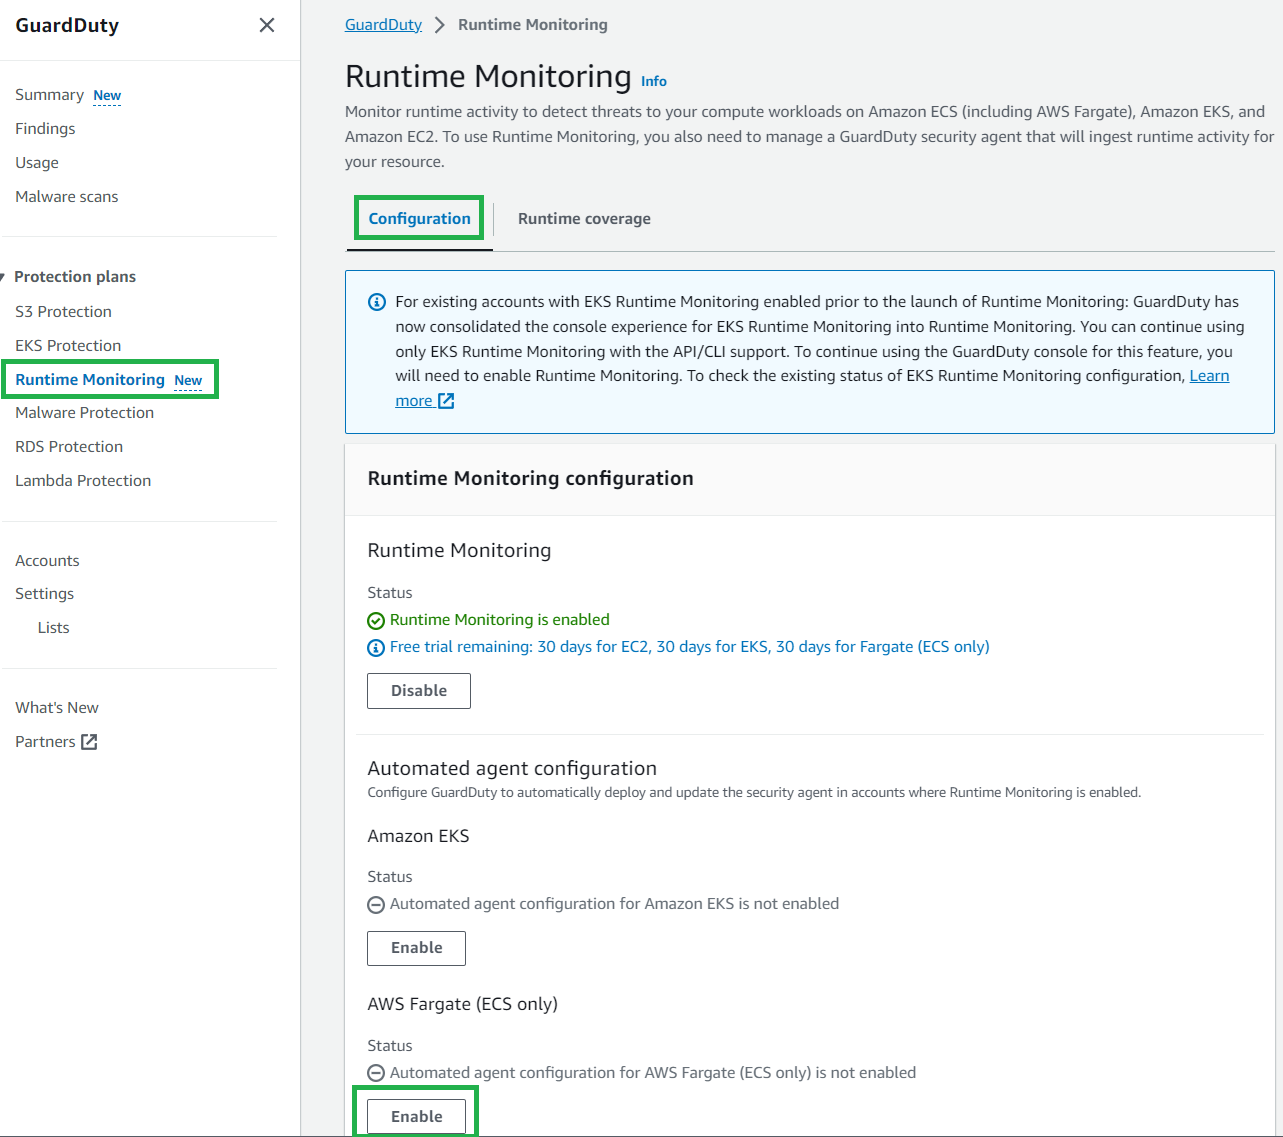
Figure 5: GuardDuty Runtime Monitoring configuration
If your AWS account is managed within AWS Organizations and you’re running ECS Fargate clusters in multiple AWS accounts, only the GuardDuty delegated administrator account can enable or disable GuardDuty ECS Runtime Monitoring for the member accounts. GuardDuty is a regional service and must be enabled within each desired Region. If you’re using multiple accounts and want to centrally manage GuardDuty see Managing multiple accounts in Amazon GuardDuty.
You can use the same process to enable GuardDuty ECS Runtime Monitoring and manage the GuardDuty security agent. It’s recommended to enable GuardDuty ECS Runtime Monitoring automatically for member accounts within your organization.
To automatically enable GuardDuty Runtime Monitoring for ECS Fargate new accounts:
- In the GuardDuty console, in the navigation pane under Protection plans, select Runtime Monitoring.
- Select the Configuration tab, and then choose Edit.
- Under Runtime Monitoring, ensure Enable for all accounts is selected.
- Under Automated agent configuration – AWS Fargate (ECS only), select Enable for all accounts, then choose Save.
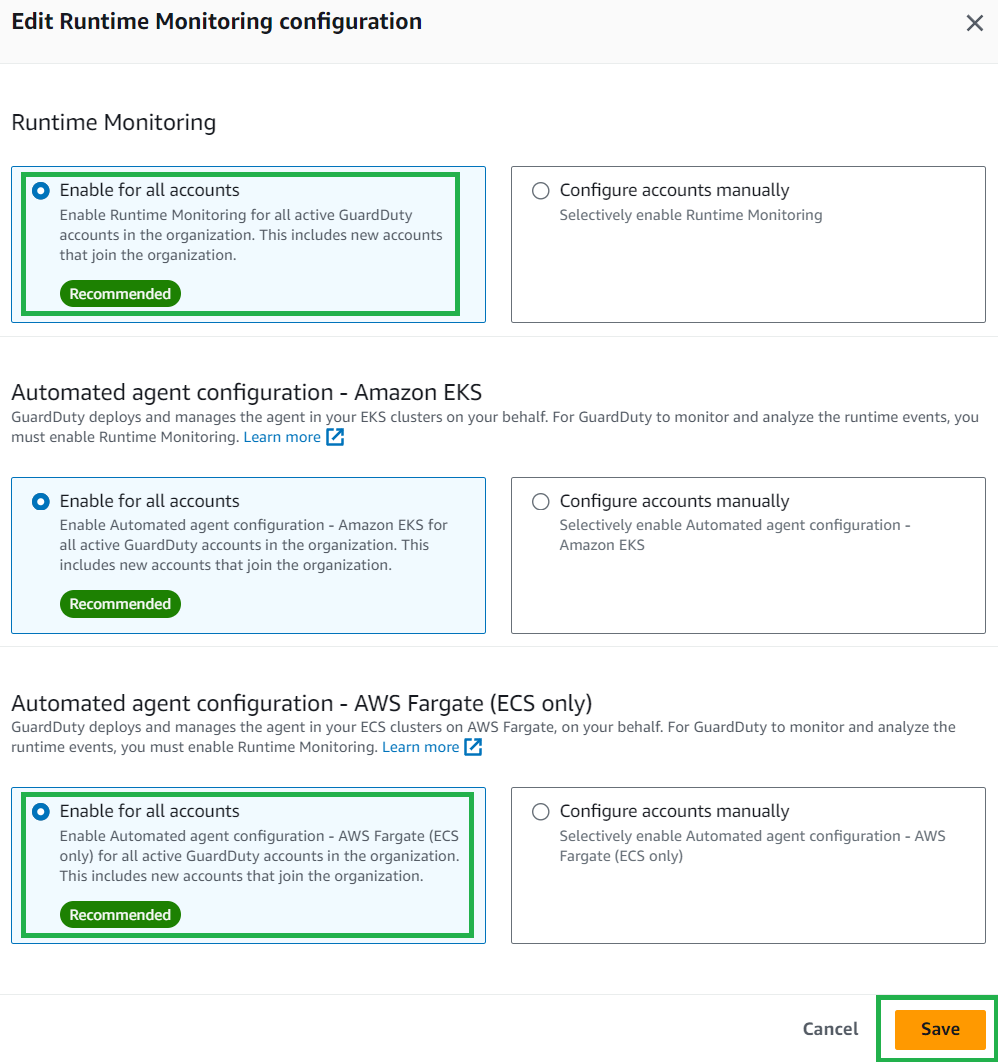
Figure 6: Enable ECS GuardDuty Runtime Monitoring for AWS accounts
After you enable GuardDuty ECS Runtime Monitoring for Fargate, GuardDuty can start monitoring and analyzing the runtime activity events for ECS tasks in your account. GuardDuty automatically creates a virtual private cloud (VPC) endpoint in your AWS account in the VPCs where you’re deploying your Fargate tasks. The VPC endpoint is used by the GuardDuty agent to send telemetry and configuration data back to the GuardDuty service API. For GuardDuty to receive the runtime events for your ECS Fargate clusters, you can choose one of three approaches to deploy the fully managed security agent:
- Monitor existing and new ECS Fargate clusters
- Monitor existing and new ECS Fargate clusters and exclude selective ECS Fargate clusters
- Monitor selective ECS Fargate clusters
It’s recommended to monitor each ECS Fargate cluster and then exclude clusters on an as-needed basis. To learn more, see Configure GuardDuty ECS Runtime Monitoring.
Monitor all ECS Fargate clusters
Use this method when you want GuardDuty to automatically deploy and manage the security agent across each ECS Fargate cluster within your account. GuardDuty will automatically install the security agent when new ECS Fargate clusters are created.
To enable GuardDuty Runtime Monitoring for ECS Fargate across each ECS cluster:
- In the GuardDuty console, in the navigation pane under Protection plans, select Runtime Monitoring.
- Select the Configuration tab.
- Under the Automated agent configuration for AWS Fargate (ECS only), select Enable.
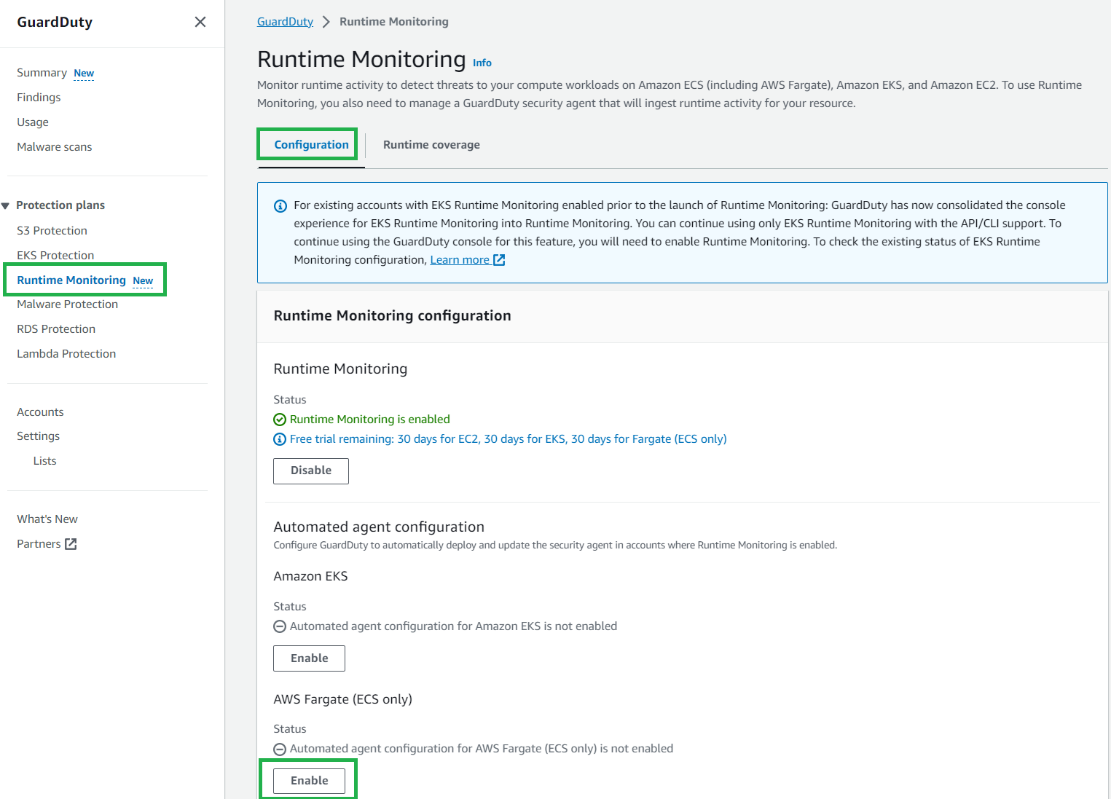
Figure 7: Enable GuardDuty Runtime Monitoring for ECS clusters
Monitor all ECS Fargate clusters and exclude selected ECS Fargate clusters
GuardDuty automatically installs the security agent on each ECS Fargate cluster. To exclude an ECS Fargate cluster from GuardDuty Runtime Monitoring, you can use the key-value pair GuardDutyManaged:false as a tag. Add this exclusion tag to your ECS Fargate cluster either before enabling Runtime Monitoring or during cluster creation to prevent automatic GuardDuty monitoring.
To add an exclusion tag to an ECS cluster:
- In the Amazon ECS console, in the navigation pane under Clusters, select the cluster name.
- Select the Tags tab.
- Select Manage Tags and enter the key GuardDutyManaged and value false, then choose Save.
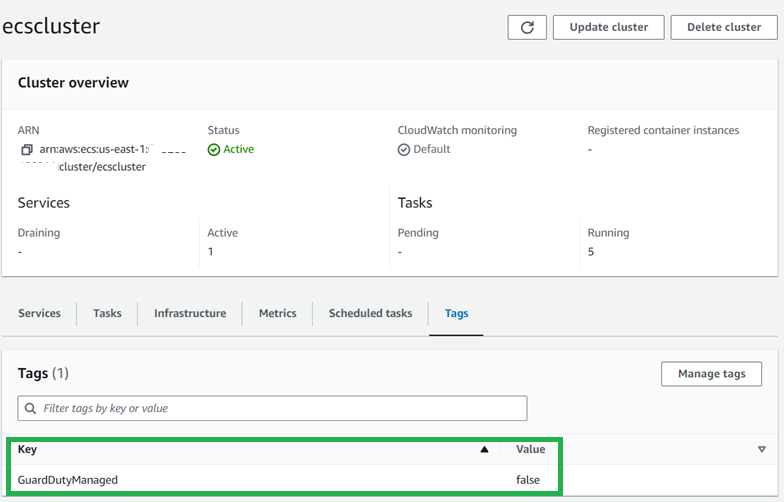
Figure 8: GuardDuty Runtime Monitoring ECS cluster exclusion tags
To make sure that these tags aren’t modified, you can prevent tags from being modified except by authorized principals.
Monitor selected ECS Fargate clusters
You can monitor selected ECS Fargate clusters when you want GuardDuty to handle the deployment and updates of the security agent exclusively for specific ECS Fargate clusters within your account. This could be a use case where you want to evaluate GuardDuty ECS Runtime Monitoring for Fargate. By using inclusion tags, GuardDuty automatically deploys and manages the security agent only for the ECS Fargate clusters that are tagged with the key-value pair GuardDutyManaged:true. To use inclusion tags, verify that the automated agent configuration for AWS Fargate (ECS) hasn’t been enabled.
To add an inclusion tag to an ECS cluster:
- In the Amazon ECS console, in the navigation pane under Clusters, select the cluster name.
- Select the Tags tab.
- Select Manage Tags and enter the key GuardDutyManaged and value true, then choose Save.
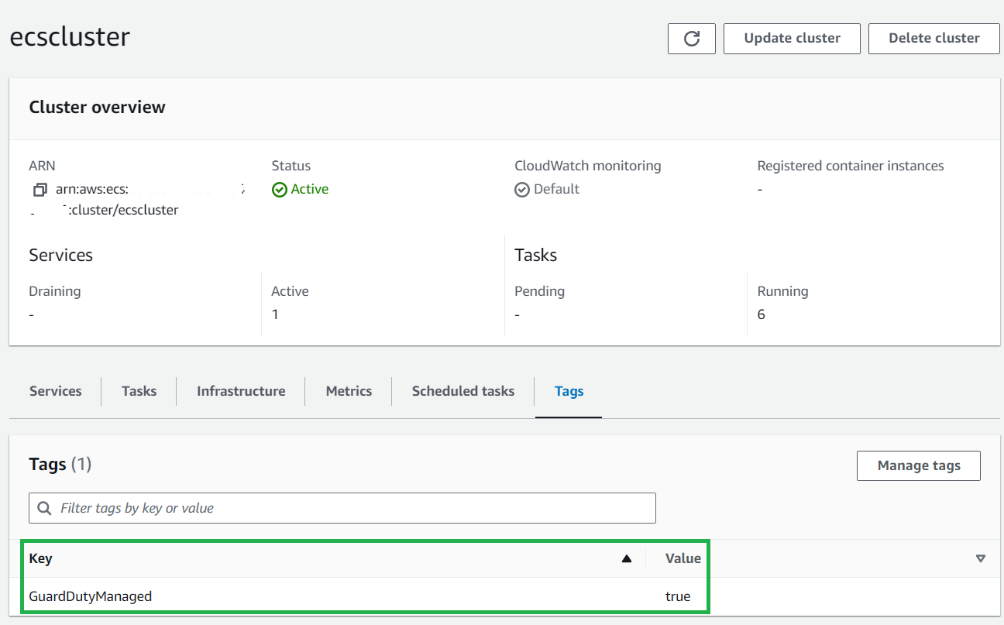
Figure 9: GuardDuty inclusion tags
To make sure that these tags aren’t modified, you can prevent tags from being modified except by authorized principals.
Fargate task level rollout
After you’re enabled GuardDuty ECS Runtime Monitoring for Fargate, newly launched tasks will include the GuardDuty agent sidecar container. For pre-existing long running tasks, you might want to consider a targeted deployment for task refresh to activate the GuardDuty sidecar security container. This can be achieved using either a rolling update (ECS deployment type) or a blue/green deployment with AWS CodeDeploy.
To verify the GuardDuty agent is running for a task, you can check for an additional container prefixed with aws-guardduty-agent-. Successful deployment will change the container’s status to Running.
To view the GuardDuty agent container running as part of your ECS task:
- In the Amazon ECS console, in the navigation pane under Clusters, select the cluster name.
- Select the Tasks tab.
- Select the Task GUID you want to review.
- Under the Containers section, you can view the GuardDuty agent container.
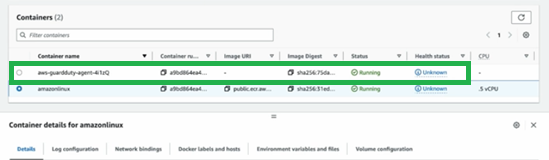
Figure 10: View status of the GuardDuty sidecar container
GuardDuty ECS on Fargate coverage monitoring
Coverage status of your ECS Fargate clusters is evaluated regularly and can be classified as either healthy or unhealthy. An unhealthy cluster signals a configuration issue, and you can find more details in the GuardDuty Runtime Monitoring notifications section. When you enable GuardDuty ECS Runtime Monitoring and deploy the security agent in your clusters, you can view the coverage status of new ECS Fargate clusters and tasks in the GuardDuty console.
To view coverage status:
- In the GuardDuty console, in the navigation pane under Protection plans, select Runtime Monitoring.
- Select the Runtime coverage tab, and then select ECS clusters runtime coverage.
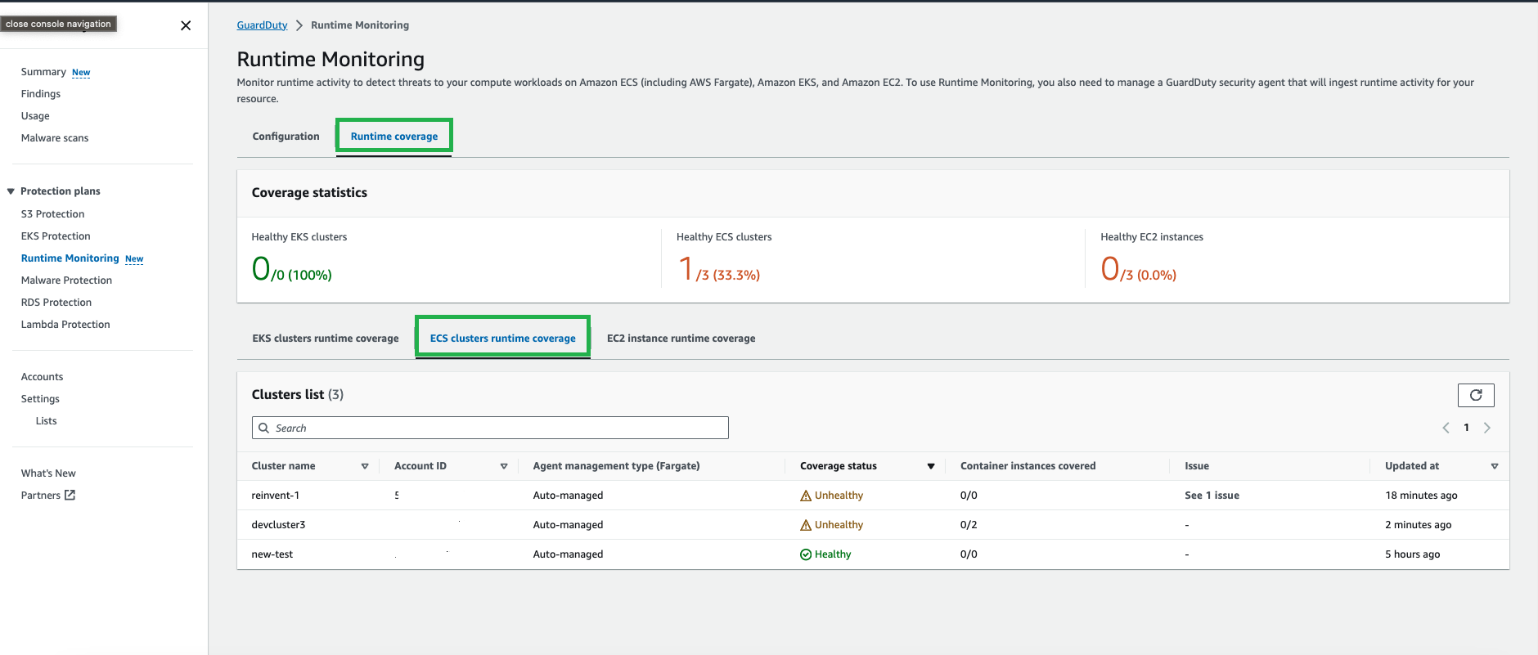
Figure 11: GuardDuty Runtime ECS coverage status overview
Troubleshooting steps for cluster coverage issues such as clusters reporting as unhealthy and a sample notification schema are available at Coverage for Fargate (Amazon ECS only) resource. More information regarding monitoring can be found in the next section.
Amazon GuardDuty Runtime Monitoring for EC2
Amazon EC2 Runtime Monitoring in GuardDuty helps you provide threat detection for Amazon EC2 instances and supports Amazon ECS managed EC2 instances. The GuardDuty security agent, which GuardDuty uses to send telemetry and configuration data back to the GuardDuty service API, is required to be installed onto each EC2 instance.
Prerequisites
If you haven’t activated Amazon GuardDuty, learn more about the free trial and pricing and follow the steps in Getting started with GuardDuty to set up the service and start monitoring your account. Alternatively, you can activate GuardDuty by using the AWS CLI.
To use Amazon EC2 Runtime Monitoring to monitor your ECS container instances, your operating environment must meet the prerequisites for EC2 instance support and the GuardDuty security agent must be installed manually onto the EC2 instances you want to monitor. GuardDuty Runtime Monitoring for EC2 requires you to create the Amazon VPC endpoint manually. If the VPC already has the GuardDuty VPC endpoint created from a previous deployment, you don’t need to create the VPC endpoint again.
If you plan to deploy the agent to Amazon EC2 instances using AWS Systems Manager, an Amazon owned Systems Manager document named AmazonGuardDuty-ConfigureRuntimeMonitoringSsmPlugin is available for use. Alternatively, you can use RPM installation scripts whether or not your Amazon ECS instances are managed by AWS Systems Manager.
Enable GuardDuty Runtime Monitoring for EC2
GuardDuty Runtime Monitoring for EC2 is automatically enabled when you enable GuardDuty Runtime Monitoring.
To enable GuardDuty Runtime Monitoring:
- In the GuardDuty console, in the navigation pane under Protection plans, select Runtime Monitoring.
- Select the Configuration tab, and then in the Runtime Monitoring section, choose Enable.
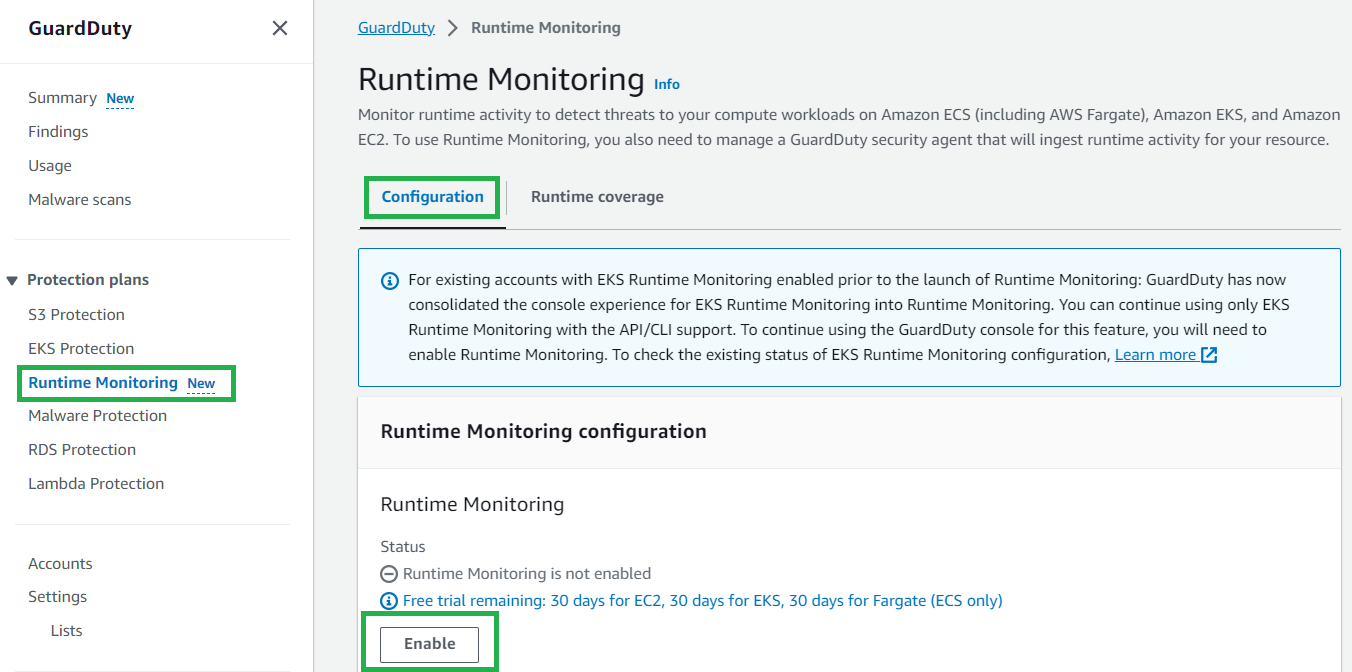
Figure 12: Enable GuardDuty runtime monitoring
After the prerequisites have been met and you enable GuardDuty Runtime Monitoring, GuardDuty starts monitoring and analyzing the runtime activity events for the EC2 instances.
If your AWS account is managed within AWS Organizations and you’re running ECS on EC2 clusters in multiple AWS accounts, only the GuardDuty delegated administrator can enable or disable GuardDuty ECS Runtime Monitoring for the member accounts. If you’re using multiple accounts and want to centrally manage GuardDuty, see Managing multiple accounts in Amazon GuardDuty.
GuardDuty EC2 coverage monitoring
When you enable GuardDuty Runtime Monitoring and deploy the security agent on your Amazon EC2 instances, you can view the coverage status of the instances.
To view EC2 instance coverage status:
- In the GuardDuty console, in the navigation pane under Protection plans, select Runtime Monitoring.
- Select the Runtime coverage tab, and then select EC2 instance runtime coverage.
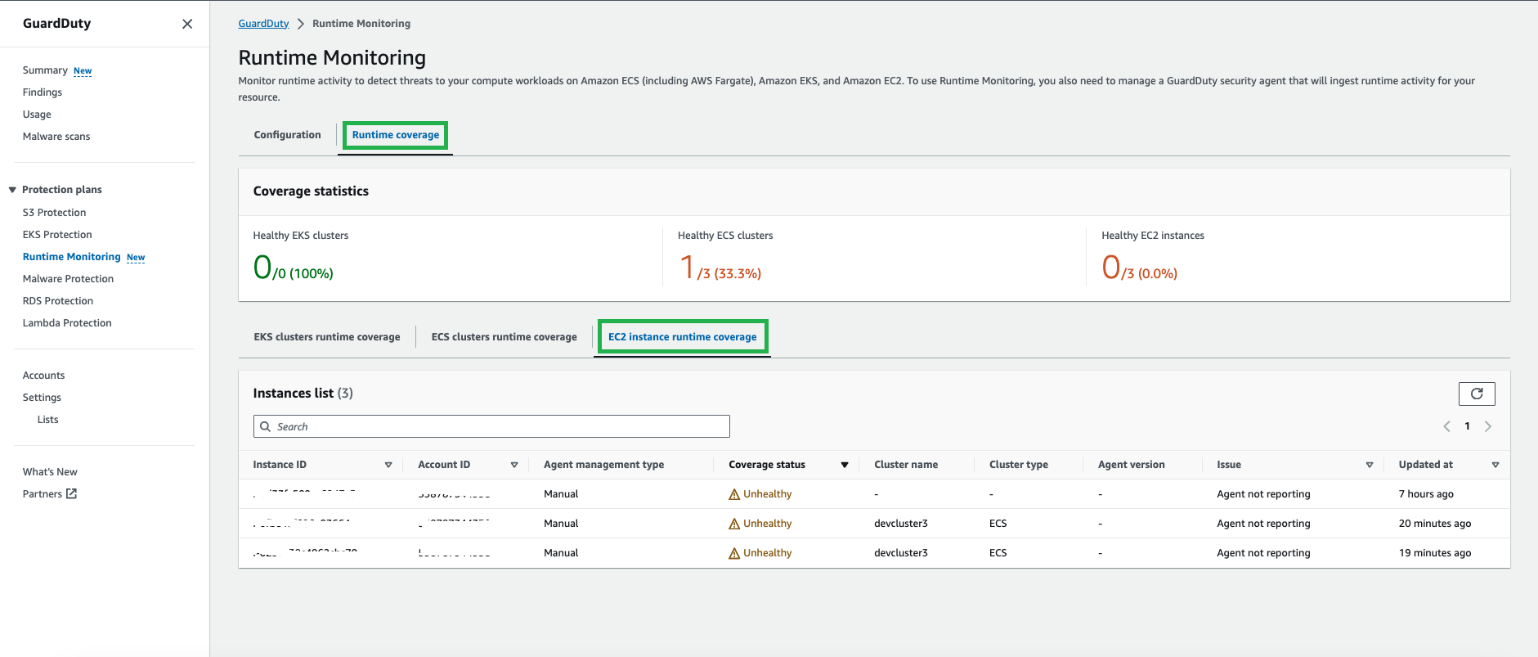
Figure 13: GuardDuty Runtime Monitoring coverage for EC2 overview
Cluster coverage status notifications can be configured using the notification schema available under Configuring coverage status change notifications. More information regarding monitoring can be found in the following section.
GuardDuty Runtime Monitoring notifications
If the coverage status of your ECS cluster or EC2 instance becomes unhealthy, there are a number of recommended troubleshooting steps that you can follow.
To stay informed about changes in the coverage status of an ECS cluster or EC2 instance, it’s recommended that you set up status change notifications. Because GuardDuty publishes these status changes on the EventBridge bus associated with your AWS account, you can do this by setting up an Amazon EventBridge rule to receive notifications.
In the following example AWS CloudFormation template, you can use an EventBridge rule to send notifications to Amazon Simple Notification Service (Amazon SNS) and subscribe to the SNS topic using email.
GuardDuty findings
When GuardDuty detects a potential threat and generates a security finding, you can view the details of the corresponding finding. The GuardDuty agent collects kernel-space and user-space events from the hosts and the containers. See Finding types for detailed information and recommended remediation activities regarding each finding type. You can generate sample GuardDuty Runtime Monitoring findings using the GuardDuty console or you can use this GitHub script to generate some basic detections within GuardDuty.
Example ECS findings
GuardDuty security findings can indicate either a compromised container workload or ECS cluster or a set of compromised credentials in your AWS environment.
To view a full description and remediation recommendations regarding a finding:
- In the GuardDuty console, in the navigation pane, select Findings.
- Select a finding in the navigation pane, and then choose the Info hyperlink.
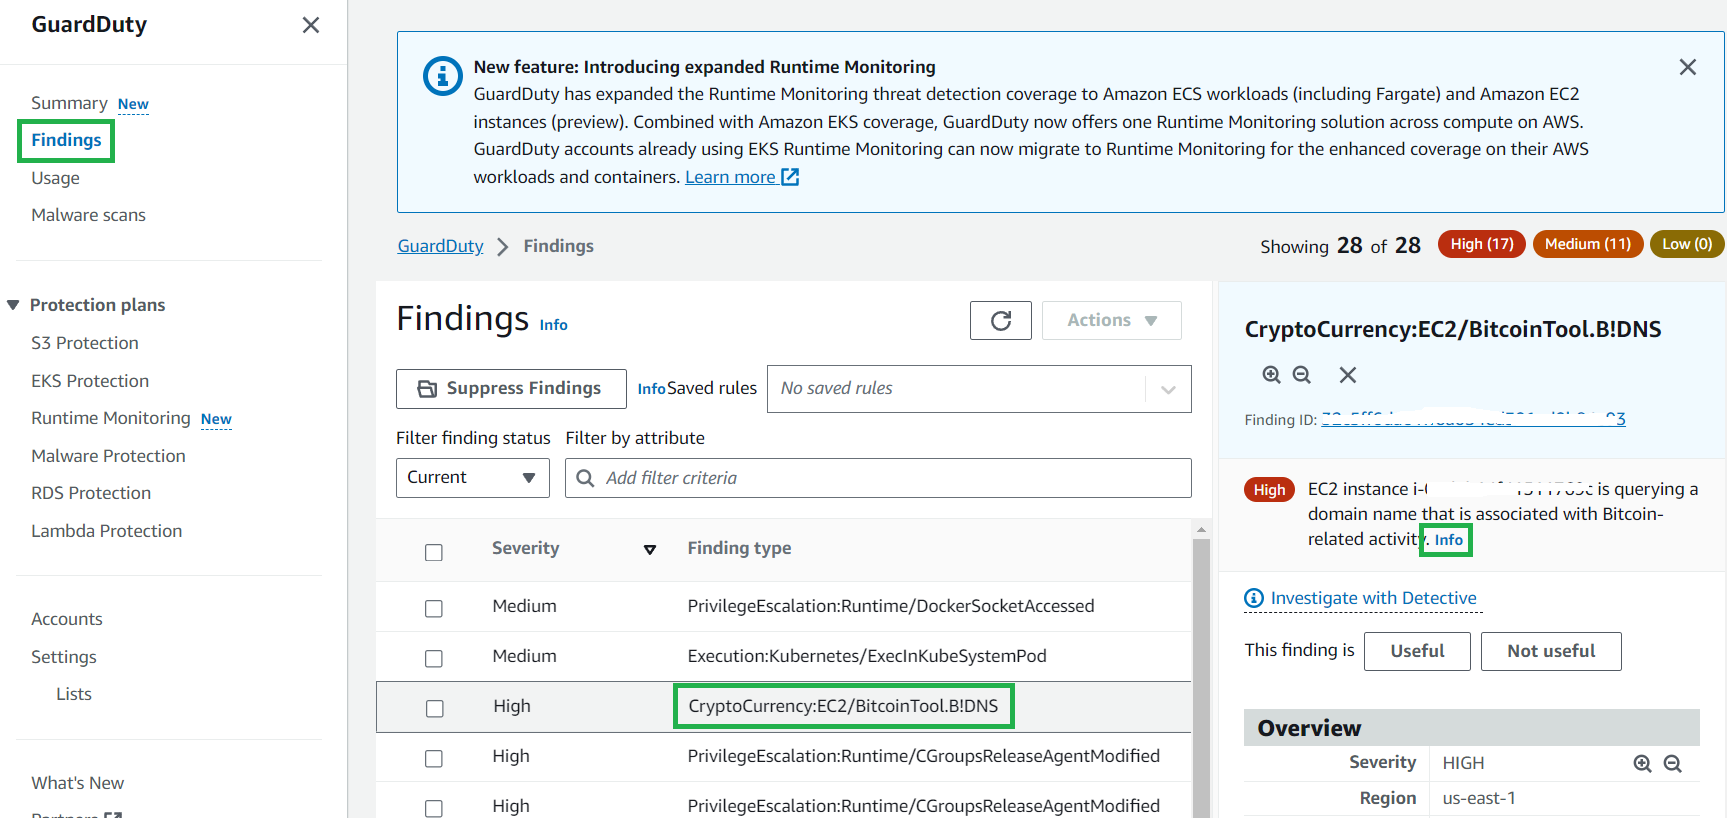
Figure 14: GuardDuty example finding
The ResourceType for an ECS Fargate finding could be an ECS cluster or container. If the resource type in the finding details is ECSCluster, it indicates that either a task or a container inside an ECS Fargate cluster is potentially compromised. You can identify the Name and Amazon Resource Name (ARN) of the ECS cluster paired with the task ARN and task Definition ARN details in the cluster.
To view affected resources, ECS cluster details, task details and instance details regarding a finding:
- In the GuardDuty console, in the navigation pane, select Findings.
- Select a finding related to an ECS cluster in the navigation pane and then scroll down in the right-hand pane to view the different section headings.
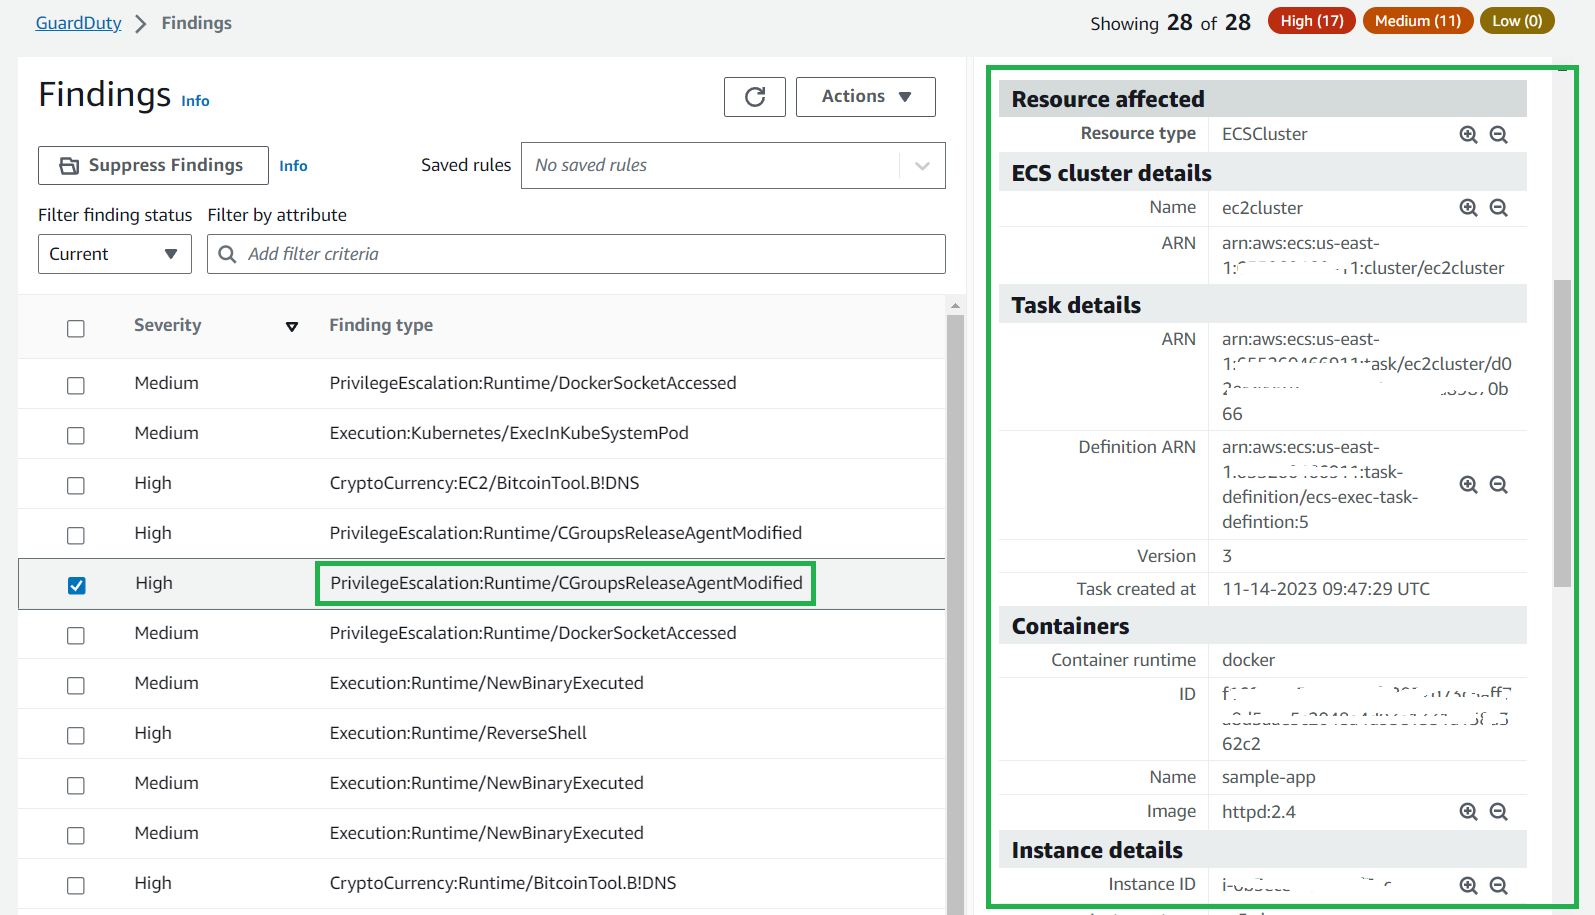
Figure 15: GuardDuty finding details for Fargate
The Action and Runtime details provide information about the potentially suspicious activity. The example finding in Figure 16 tells you that the listed ECS container in your environment is querying a domain that is associated with Bitcoin or other cryptocurrency-related activity. This can lead to threat actors attempting to take control over the compute resource to repurpose it for unauthorized cryptocurrency mining.
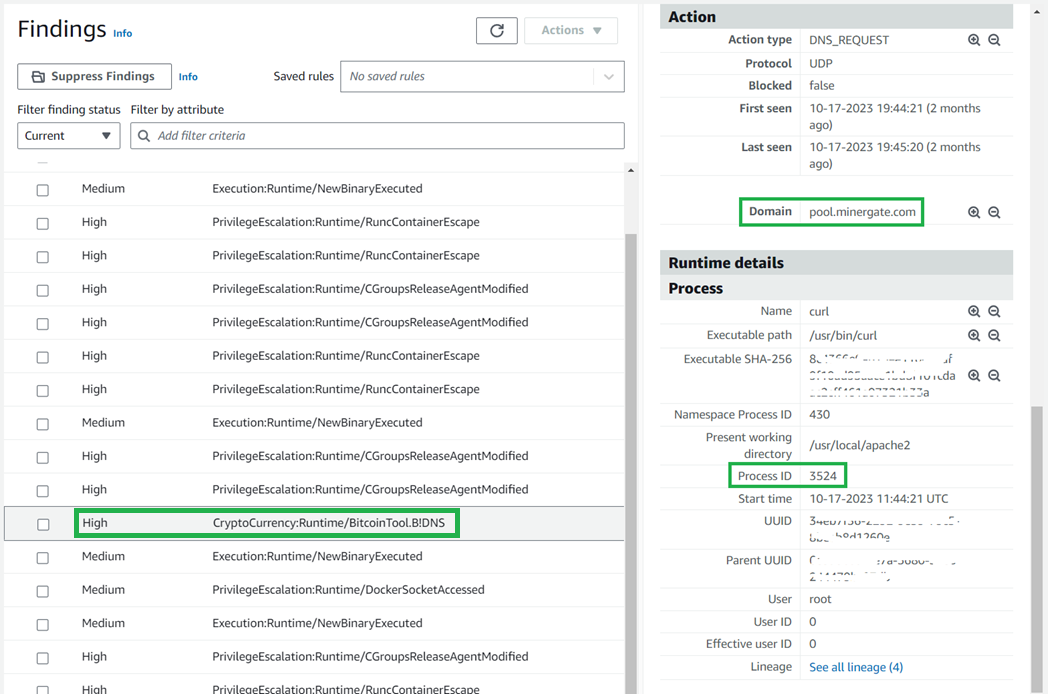
Figure 16: GuardDuty ECS example finding with action and process details
Example ECS on EC2 findings
When a finding is generated from EC2, additional information is shown including the instance details, IAM profile details, and instance tags (as shown in Figure 17), which can be used to help identify the affected EC2 instance.
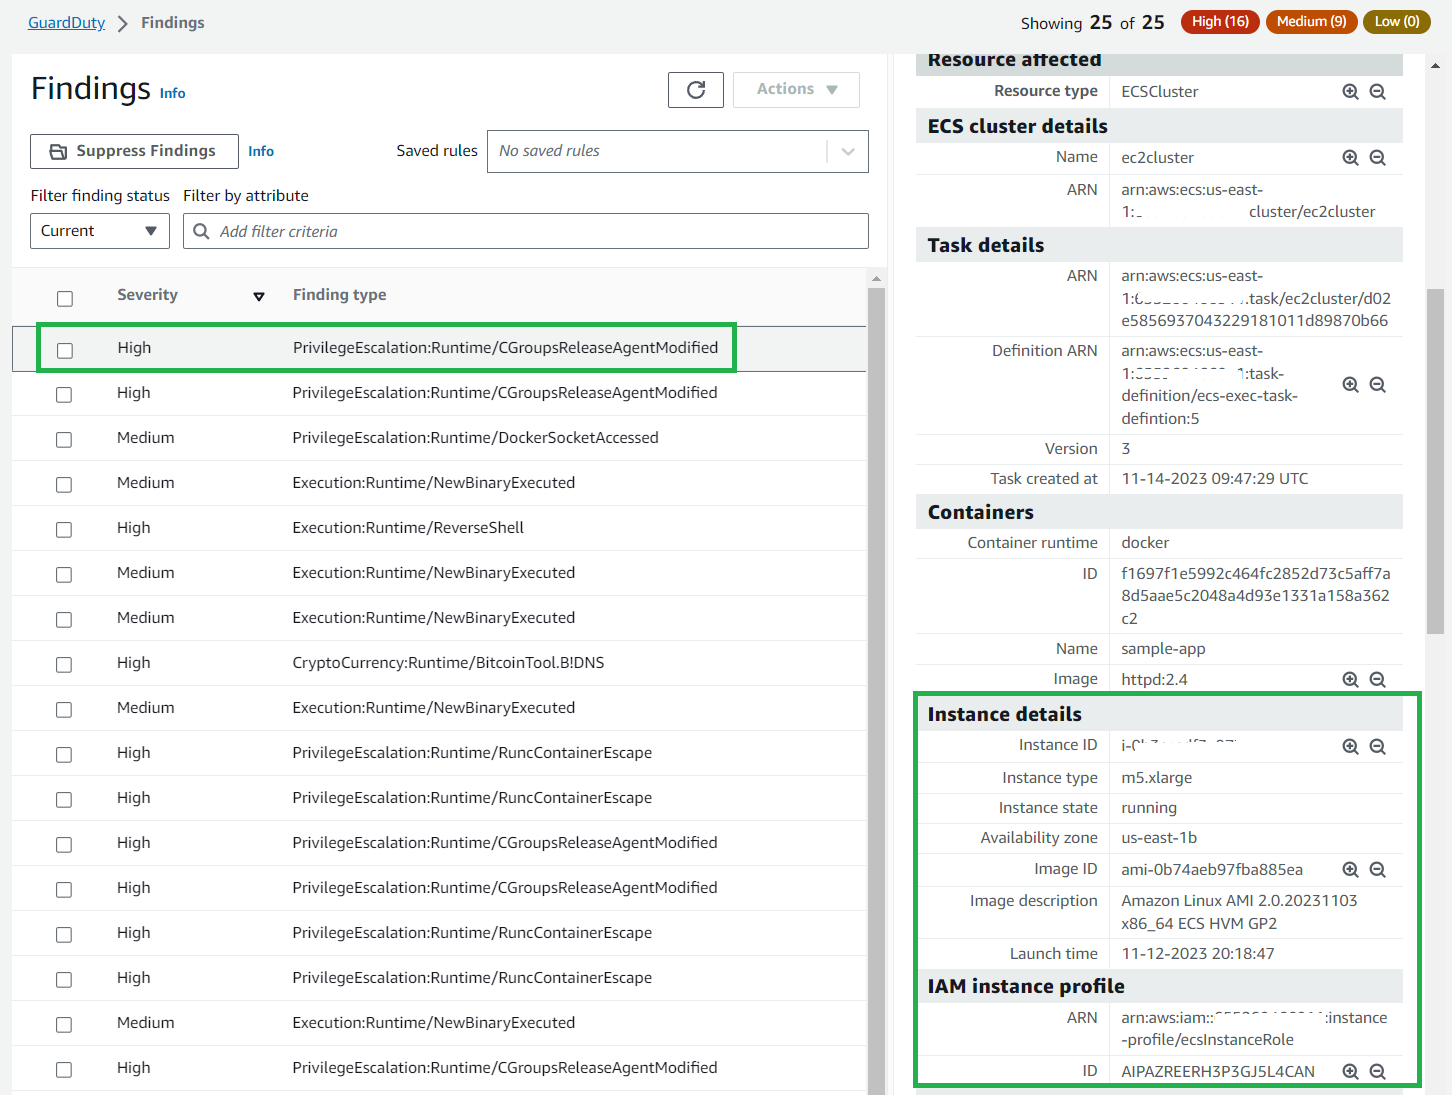
Figure 17: GuardDuty EC2 instance details for a finding
This additional instance-level information can help you focus your remediation efforts.
GuardDuty finding remediation
When you’re actively monitoring the runtime behavior of containers within your tasks and GuardDuty identifies potential security issues within your AWS environment, you should consider taking the following suggested remediation actions. This helps to address potential security issues and to contain the potential threat in your AWS account.
- Identify the potentially impacted Amazon ECS Cluster – The runtime monitoring finding provides the potentially impacted Amazon ECS cluster details in the finding details panel.
- Evaluate the source of potential compromise – Evaluate if the detected finding was in the container’s image. If the resource was in the container image, identify all other tasks that are using this image and evaluate the source of the image.
- Isolate the impacted tasks – To isolate the affected tasks, restrict both incoming and outgoing traffic to the tasks by implementing VPC network rules that deny all traffic. This approach can be effective in halting an ongoing attack by cutting off all connections to the affected tasks. Be aware that terminating the tasks could eliminate crucial evidence related to the finding that you might need for further analysis.If the task’s container has accessed the underlying Amazon EC2 host, its associated instance credentials might have been compromised. For more information, see Remediating compromised AWS credentials.
Each GuardDuty Runtime Monitoring finding provides specific prescriptive guidance regarding finding remediation. Within each finding, you can choose the Remediating Runtime Monitoring findings link for more information.
To view the recommended remediation actions:
- In the GuardDuty console, in the navigation pane, select Findings.
- Select a finding in the navigation pane and then choose the Info hyperlink and scroll down in the right-hand pane to view the remediation recommendations section.
Figure 18: GuardDuty Runtime Monitoring finding remediation
Summary
You can now use Amazon GuardDuty for ECS Runtime Monitoring to monitor your Fargate and EC2 workloads. For a full list of Regions where ECS Runtime Monitoring is available, see Region-specific feature availability.
It’s recommended that you asses your container application using the AWS Well-Architected Tool to ensure adherence to best practices. The recently launched AWS Well-Architected Amazon ECS Lens offers a specialized assessment for container-based operations and troubleshooting of Amazon ECS applications, aligning with the ECS best practices guide. You can integrate this lens into the AWS Well-Architected Tool available in the console.
For more information regarding security monitoring and threat detection, visit the AWS Online Tech Talks. For hands-on experience and learn more regarding AWS security services, visit our AWS Activation Days website to find a workshop in your Region.
If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, contact AWS Support.
Want more AWS Security news? Follow us on Twitter.
Travel Routers Improve Your Life! Beryl AX Complete Setup
Post Syndicated from Crosstalk Solutions original https://www.youtube.com/watch?v=szqme3j7h10
Mastering Industrial Cybersecurity: The Significance of Combining Vulnerability Management with Detection and Response
Post Syndicated from Rapid7 original https://blog.rapid7.com/2023/12/28/mastering-industrial-cybersecurity-the-significance-of-combining-vulnerability-management-with-detection-and-response/
Written by Elad Ben-Meir, CEO SCADAfence, a Honeywell company.
In today’s digital era, where industries are increasingly reliant on advanced technologies, safeguarding critical infrastructure against cyber threats has become paramount. The convergence of operational technology (OT) and information technology (IT) has ushered in new efficiencies but has also exposed vulnerabilities. This article explores the pivotal role of Vulnerability Management and Detection and Response (VM/DR) in the realm of Industrial Cybersecurity.
Introduction to Industrial Cybersecurity
In an interconnected world, the importance of cybersecurity cannot be overstated. In industrial settings, where the consequences of cyberattacks can extend beyond data breaches to impact physical safety and operational continuity, cybersecurity is a top priority. This article delves into the significance of VM/DR in fortifying industrial cybersecurity defenses.
Vulnerability Management and Detection and Response (VM/DR) in Industrial Context
VM/DR are not mere buzzwords, but a proactive strategy to combat the ever-evolving cyber threats facing industrial organizations and the small talent pool from which they hire. It entails continuous monitoring, rapid threat detection, and efficient incident response while understanding the industrial processes these technologies control. In the context of industrial operations, VM/DR takes on added significance as it safeguards critical processes from disruption.
The Core Components of Industrial VM/DR
A successful VM/DR program in an industrial setting comprises several key components:
- Real-time threat monitoring: This involves continuous surveillance of network traffic and system activities to detect anomalies and potential threats.
- Incident detection and analysis: Rapid identification and thorough analysis of security incidents are crucial for timely response and mitigation.
- Incident response and remediation: An effective response strategy is vital to minimize the impact of cyber incidents and promptly restore normal operations.
These components work in tandem to provide a comprehensive security shield against industrial cyber threats.
Utilizing SCADAfence’s real-time passive threat monitoring alongside Rapid7’s InsightVM and InsightIDR products allows for industrial–focused threats to be detected, analyzed, responded to, and remediated in a timely manner.
Industrial-Specific Threats and Vulnerabilities
In the industrial landscape, cyber threats go beyond traditional IT concerns. Attack vectors extend to Industrial Control Systems (ICS), which govern critical processes. Vulnerabilities unique to OT systems, such as legacy equipment and proprietary protocols, pose additional challenges. Understanding these threats is essential for effective protection.
The Landscape of Industrial Threats and Vulnerabilities
Industrial systems are the backbone of modern society, controlling everything from power grids to manufacturing processes. With connectivity becoming ubiquitous, these systems have become prime targets for malicious actors.
Reference: According to a report by IBM X-Force, attacks on industrial systems increased by over 2000% in 2020, highlighting the growing threat landscape in the industrial sector.
Legacy Systems and Proprietary Protocols
Many industrial environments still rely on legacy systems that were not designed with modern cybersecurity in mind. These aging systems often run on proprietary protocols, making them vulnerable to exploitation.
Reference: The Industrial Control Systems Cyber Emergency Response Team (ICS-CERT) has noted an increase in vulnerabilities related to legacy systems and proprietary protocols in their annual reports.
Human Error and Insider Threats
Human error remains a significant factor in industrial incidents. Insider threats, whether intentional or unintentional, can have catastrophic consequences in industrial settings.
Reference: A study by Ponemon Institute found that 57% of industrial organizations surveyed had experienced at least one insider threat incident in the past year.
Supply Chain Vulnerabilities
Industrial systems rely on a complex network of suppliers and vendors. Weak links in the supply chain can introduce vulnerabilities that adversaries could exploit.
Reference: The U.S. Cybersecurity and Infrastructure Security Agency (CISA) has issued alerts about supply chain vulnerabilities in industrial control systems.
IoT and Edge Devices
The proliferation of Internet of Things (IoT) devices and edge computing has expanded the attack surface in industrial environments. These devices are often inadequately secured.
Reference: A report from Kaspersky highlights a 46% increase in attacks on IoT devices in the first half of 2020, with many incidents affecting industrial sectors.
Ransomware Targeting Critical Infrastructure
Ransomware attacks have evolved to target critical infrastructure, disrupting essential services and demanding hefty ransoms.
Reference: The Colonial Pipeline ransomware attack in May 2021 brought widespread attention to the threat of ransomware against critical infrastructure.
Integration with Existing Workflows/Playbooks
VM/DR is not a standalone solution but a complement to existing industrial workflows and/or playbooks. It bridges the gap between IT and OT, breaking down silos that often hinder effective cybersecurity. By integrating VM/DR seamlessly into existing processes, organizations can enhance their ability to promptly respond to threats. Having detailed playbooks with key operational Points of Contact (POC) helps to reduce dead time when dealing with a business and process interruption inside of an industrial process.
Implementing response and action plans within the current organization’s workflows helps analysts better communicate in the operational verbiage and expedites remediations directly in the field. This alleviates IT’s need for Confidentiality, Integrity, and Availability (CIA) and supports OT’s requirements for Availability, Integrity, Confidentiality (AIC).
Measuring Success with Key Performance Indicators (KPIs)
Success in industrial VM/DR can be quantified through various KPIs:
- Time to detect (TTD): The speed at which threats are identified
- Time to Respond (TTR): The efficiency of incident response
- Incident Resolution Rate: The effectiveness of mitigation efforts
These KPIs provide a tangible measure of an organization’s cybersecurity resilience.
Collaboration between IT and OT
The collaboration between IT and OT teams is pivotal in industrial cybersecurity. VM/DR serves as a unifying force, facilitating communication and coordination between these traditionally separate domains. This collaboration is vital for the timely identification and mitigation of threats.
Compliance and Regulatory Considerations
Industrial organizations are subject to various cybersecurity regulations and standards such as the North American Electric Reliability Corporation Critical Infrastructure Protection (NERC CIP). NERC CIP regulatory compliance is a set of mandatory cybersecurity standards and requirements designed to safeguard the North American power grid’s critical infrastructure.
These regulations are a response to the increasing cybersecurity threats faced by the energy sector. NERC CIP compliance mandates that electric utilities and power generation companies establish and maintain robust cybersecurity programs, including measures such as access controls, incident response planning, and regular security assessments. The primary goal of NERC CIP is to ensure the reliable operation of the electric grid while minimizing vulnerabilities to cyberattacks, thus safeguarding the continuous supply of electricity to homes, businesses, and critical infrastructure across North America. Compliance with NERC CIP is essential to maintain the security and resilience of the energy sector in the face of evolving cybersecurity threats.
Implementing a compliance governance portal is a strategic move for organizations seeking to streamline and centralize their compliance management efforts. Such a portal serves as a centralized platform where compliance policies, procedures, and documentation can be efficiently stored, accessed, and monitored. It facilitates real-time tracking of compliance activities, automates workflow processes, and provides a comprehensive view of the organization’s adherence to regulatory requirements.
This not only enhances transparency and accountability but also simplifies reporting and auditing. The implementation of a compliance governance portal empowers organizations to proactively manage risk, ensure regulatory adherence, and respond swiftly to compliance-related challenges, ultimately fostering a culture of compliance throughout the organization. VM/DR plays a crucial role in helping organizations meet compliance requirements, providing assurance to regulators and stakeholders.
Securing the Future
In the face of relentless cyber threats, mastering industrial cybersecurity is not a luxury – it’s a necessity. VM/DR is the linchpin that empowers organizations to fortify their defenses, protect critical infrastructure, and ensure operational continuity in an increasingly digital world.
As digital transformation continues, industrial VM/DR represents a proactive, adaptive, and collaborative approach to safeguarding the backbone of our society. It’s time for industrial organizations to embrace VM/DR and secure their future.
[$] The Linux graphics stack in a nutshell, part 2
Post Syndicated from jake original https://lwn.net/Articles/955708/
Displaying an application’s graphical output onto the screen requires
compositing and
mode setting that are correctly synchronized among the various pieces,
with low overhead.
In this second and final article in the series, we will look at
those pieces of the Linux graphics stack. In the first installment, we
followed the path of graphics from the application, through Mesa, while
using the
memory-management features of the kernel’s Direct
Rendering Manager (DRM) subsystem.
We ended up with an application’s graphics data stored in an output buffer,
so now
it’s time to display the image to the user.