Developers working with Amazon Managed Streaming for Apache Kafka (Amazon MSK) regularly need to make decisions that require deep operational context—choosing the right instance type, diagnosing consumer lag, or planning for a traffic spike. Answering these questions means piecing together documentation, metrics, and operational know-how.
What if your IDE could guide you through that workflow with built-in domain expertise and tooling? Kiro is an AI-powered agentic IDE that lets you describe what you need in natural language. Whether it’s infrastructure configuration or operational troubleshooting, Kiro guides you through the solution.
In this post, we’ll show you how to use Kiro powers, a new capability that equips Kiro with contextual knowledge and tooling. You can simplify your MSK cluster management, from initial setup to diagnosing common issues, all through natural language conversations.
Challenges operating your MSK Express broker cluster
Amazon MSK Express Brokers are a fully managed offering where AWS handles much of the underlying infrastructure. However, platform teams still need to correctly size clusters based on throughput requirements. They also need to understand the right Amazon CloudWatch metrics during performance issues and investigate when CPU usage or replication lag is higher than expected. MSK best practices documentation spans multiple AWS guides. This makes it time-consuming to find relevant information during production incidents. New team members face a learning curve with MSK operations and can repeat common sizing and configuration mistakes.
Although Express Brokers simplify infrastructure management, you still face operational challenges that require deep Kafka expertise across three areas:
Cluster creation and sizing: You must still select the right instance type, configure networking, and choose authentication methods. These decisions impact cost and performance from day one.
Observability and troubleshooting: Effective operations require correlating broker, partition, and client metrics. Troubleshooting lag or replication issues still requires a solid understanding of Express Brokers’ architecture.
Capacity management: You must monitor CPU usage, understand per-broker throughput limits, and scale before hitting throttling thresholds.
These challenges mean that setting up an MSK cluster, analyzing slow-running clients, or investigating high-CPU load requires pulling together documentation, configuration details, CLI tooling, and operational know-how, which is often spread across multiple sources. Kiro powers address these challenges by bringing best practices, guided workflows, and tooling directly into your IDE, reducing the expertise barrier and the time spent context-switching between documentation, consoles, and the CLI.
Kiro powers
Kiro powers is a feature that combines best practices, specialized context, and tool integrations into a single capability. You can install powers with one click in the Kiro IDE or add them from a public GitHub URL. Each Power combines the following components:
Model Context Protocol (MCP) servers give your Kiro agent direct access to your infrastructure. The AWS MSK MCP server, for example, exposes tools to create clusters, monitor health, and optimize configurations.
Steering files provide persistent knowledge and workflow guides that Kiro loads based on the user’s task, such as monitoring best practices or troubleshooting workflows.
Optional hooks run automated actions when IDE events occur, such as validating configurations before deployment.
The key advantage of Kiro powers is that they load context dynamically based on the user’s task. Instead of configuring every MCP server upfront and re-providing context in each conversation, powers activate the right tools and knowledge on demand. This keeps your agent’s context focused and relevant. In the next section, we look at how these components work together specifically for MSK Express Broker operations.
The MSK Express broker power
The MSK Express broker power packages the AWS MSK MCP server with targeted streaming operations guidance, giving your Kiro agent expertise for MSK Express Broker operations and cluster management. You can use it to build Kafka-based streaming applications through Kiro while maintaining Express broker best practices throughout the development lifecycle.
For cluster operations, you can create Express broker clusters, monitor health metrics, and manage configurations through natural language. You can retrieve cluster metadata, check broker endpoints, and verify replication status. The Power also supports operational monitoring. You can track CPU utilization, throughput limits, partition distribution, and AWS Identity and Access Management (IAM) connection metrics.
To see how this works in practice, here’s what happens when you interact with the Power: When you ask Kiro to create an MSK cluster, the Power recommends appropriate instance sizes based on your throughput requirements. When you’re troubleshooting, it knows to check LeaderCount before diving into network metrics. When you’re troubleshooting authentication failures, it recommends client settings like reconnect.backoff.ms and group.instance.id to resolve connection churn and rebalancing issues against Express broker limits. Use cases include:
Cluster sizing and creation: Describe your throughput requirements (for example, “50 MBps ingress with 3x fan-out”) and the Power calculates the right instance type and broker count, then walks through cluster creation.
Proactive health monitoring: Ask Kiro to review your cluster. It checks CPU against the 60% threshold, compares throughput to instance limits, and flags partition imbalances and throughput bottlenecks before they become incidents.
Incident troubleshooting: Consumer lag spiking? The Power checks the relevant metrics, identifies the root cause (like skewed partition leadership), and guides you through resolution.
Capacity planning: Preparing for a traffic spike? The Power analyzes current utilization against instance limits and recommends whether to scale up or add brokers.
The MSK Express broker power brings together documentation, metrics, and operational context so your Kiro agent can correlate findings and help identify root causes specific to your infrastructure.
Getting started with the MSK Express broker power
Starting with Kiro powers takes only a few clicks in the Kiro IDE. You can install from the built-in marketplace or import from a public GitHub URL. Kiro packages all components and makes them available to the Kiro agent.
To set up the MSK Express broker power, follow these steps:
Choose the Powers icon in the Kiro sidebar
In the AVAILABLE panel, scroll down to Build and Operate MSK Express Broker
The MSK Express broker power streamlines Kafka operations by combining Model Context Protocol (MCP) servers with operational guidance. With natural language interactions, you can create clusters, monitor health, optimize configurations, and troubleshoot issues without reviewing extensive documentation.
Validating Kafka configurations before production deployment can be challenging. In this post, we introduce the workload simulation workbench for Amazon Managed Streaming for Apache Kafka (Amazon MSK) Express Broker. The simulation workbench is a tool that you can use to safely validate your streaming configurations through realistic testing scenarios.
Solution overview
Varying message sizes, partition strategies, throughput requirements, and scaling patterns make it challenging for you to predict how your Apache Kafka configurations will perform in production. The traditional approaches to test these variables create significant barriers: ad-hoc testing lacks consistency, manual set up of temporary clusters is time-consuming and error-prone, production-like environments require dedicated infrastructure teams, and team training often happens in isolation without realistic scenarios. You need a structured way to test and validate these configurations safely before deployment. The workload simulation workbench for MSK Express Broker addresses these challenges by providing a configurable, infrastructure as code (IaC) solution using AWS Cloud Development Kit (AWS CDK) deployments for realistic Apache Kafka testing. The workbench supports configurable workload scenarios, and real-time performance insights.
Express brokers for MSK Provisioned make managing Apache Kafka more streamlined, more cost-effective to run at scale, and more elastic with the low latency that you expect. Each broker node can provide up to 3x more throughput per broker, scale up to 20x faster, and recover 90% quicker compared to standard Apache Kafka brokers. The workload simulation workbench for Amazon MSK Express broker facilitates systematic experimentation with consistent, repeatable results. You can use the workbench for multiple use cases like production capacity planning, progressive training to prepare developers for Apache Kafka operations with increasing complexity, and architecture validation to prove streaming designs and compare different approaches before making production commitments.
Architecture overview
The workbench creates an isolated Apache Kafka testing environment in your AWS account. It deploys a private subnet where consumer and producer applications run as containers, connects to a private MSK Express broker and monitors for performance metrics and visibility. This architecture mirrors the production deployment pattern for experimentation. The following image describes this architecture using AWS services.
This architecture is deployed using the following AWS services:
Amazon Elastic Container Service (Amazon ECS)generate configurable workloads with Java-based producers and consumers, simulating various real-world scenarios through different message sizes and throughput patterns.
Dynamic Amazon CloudWatch Dashboards automatically adapt to your configuration, displaying real-time throughput, latency, and resource utilization across different test scenarios.
The workbench provides different configuration options for your Apache Kafka testing environment, so you can customize instance types, broker count, topic distribution, message characteristics, and ingress rate. You can adjust the number of topics, partitions per topic, sender and receiver service instances, and message sizes to match your testing needs. These flexible configurations support two distinct testing approaches to validate different aspects of your Kafka deployment:
Test different workload patterns against the same MSK Express cluster configuration. This is useful for comparing partition strategies, message sizes, and load patterns.
Approach 2: Infrastructure rightsizing (redeploy and compare)
Test different MSK Express cluster configurations by redeploying the workbench with different broker settings while keeping the same workload. This is recommended for rightsizing experiments and understanding the impact of vertical compared to horizontal scaling.
// Baseline: Deploy and test
export const mskBrokerConfig: MskBrokerConfig = { numberOfBrokers: 1, instanceType: 'express.m7g.large',};

// Vertical scaling: Redeploy with larger instances
export const mskBrokerConfig: MskBrokerConfig = { numberOfBrokers: 1,
instanceType: 'express.m7g.xlarge', // Larger instances
};

// Horizontal scaling: Redeploy with more brokers
export const mskBrokerConfig: MskBrokerConfig = {
numberOfBrokers: 2, // More brokers
instanceType: 'express.m7g.large',};
Each redeployment uses the same workload configuration, so you can isolate the impact of infrastructure changes on performance.
Workload testing scenarios (single deployment)
These scenarios test different workload patterns against the same MSK Express cluster:
Partition strategy impact testing
Scenario: You are debating the usage of fewer topics with many partitions compared to many topics with fewer partitions for your microservices architecture. You want to understand how partition count affects throughput and consumer group coordination before making this architectural decision.
Scenario: Your application handles different types of events – small IoT sensor readings (256 bytes), medium user activity events (1 KB), and large document processing events (8KB). You must understand how message size impacts your overall system performance and if you should separate these into different topics or handle them together.
Scenario: You expect traffic to vary significantly throughout the day, with peak loads requiring 10× more processing capacity than off-peak hours. You want to validate how your Apache Kafka topics and partitions handle different load levels and understand the performance characteristics before production deployment.
Infrastructure rightsizing experiments (redeploy and compare)
These scenarios help you understand the impact of different MSK Express cluster configurations by redeploying the workbench with different broker settings:
MSK broker rightsizing analysis
Scenario: You deploy a cluster with basic configuration and put load on it to establish baseline performance. Then you want to experiment with different broker configurations to see the effect of vertical scaling (larger instances) and horizontal scaling (more brokers) to find the right cost-performance balance for your production deployment.
// Redeploy: Test vertical scaling impact
export const mskBrokerConfig: MskBrokerConfig = {
numberOfBrokers: 1, // Same broker count
instanceType: 'express.m7g.xlarge', // Larger instances
};

// Keep same workload configuration to compare results
Step 3: Redeploy with horizontal scaling
// Redeploy: Test horizontal scaling impact
export const mskBrokerConfig: MskBrokerConfig = {
numberOfBrokers: 2, // 6 total brokers (2 per AZ)
instanceType: 'express.m7g.large', // Back to original size
};

// Keep same workload configuration to compare results
This rightsizing approach helps you understand how broker configuration changes affect the same workload, so you can improve both performance and cost for your specific requirements.
Performance insights
The workbench provides detailed insights into your Apache Kafka configurations through monitoring and analytics, creating a CloudWatch dashboard that adapts to your configuration. The dashboard starts with a configuration summary showing your MSK Express cluster details and workbench service configurations, helping you to understand what you’re testing. The following image shows the dashboard configuration summary:
The second section of dashboard shows real-time MSK Express cluster metrics including:
Broker performance: CPU utilization and memory usage across brokers in your cluster
Network activity: Monitor bytes in/out and packet counts per broker to understand network utilization patterns
Connection monitoring: Displays active connections and connection patterns to help identify potential bottlenecks
Resource utilization: Broker-level resource tracking provides insights into overall cluster health
The following image shows the MSK cluster monitoring dashboard:
The third section of the dashboard shows the Intelligent Rebalancing and Cluster Capacity insights showing:
Intelligent rebalancing: in progress: Shows whether a rebalancing operation is currently in progress or has occurred in the past. A value of 1 indicates that rebalancing is actively running, while 0 means that the cluster is in a steady state.
Cluster under-provisioned: Indicates whether the cluster has insufficient broker capacity to perform partition rebalancing. A value of 1 means that the cluster is under-provisioned and Intelligent Rebalancing can’t redistribute partitions until more brokers are added or the instance type is upgraded.
Global partition count: Displays the total number of unique partitions across all topics in the cluster, excluding replicas. Use this to track partition growth over time and validate your deployment configuration.
Leader count per broker: Shows the number of leader partitions assigned to each broker. An uneven distribution indicates partition leadership skew, which can lead to hotspots where certain brokers handle disproportionate read/write traffic.
Partition count per broker: Shows the total number of partition replicas hosted on each broker. This metric includes both leader and follower replicas and is key to identifying replica distribution imbalances across the cluster.
The following image shows the Intelligent Rebalancing and Cluster Capacity section of the dashboard:
The fourth section of the dashboard shows the application-level insights showing:
System throughput: Displays the total number of messages per second across services, giving you a complete view of system performance
Service comparisons: Performs side-by-side performance analysis of different configurations to understand which approaches fit
Individual service performance: Each configured service has dedicated throughput tracking widgets for detailed analysis
Latency analysis: The end-to-end message delivery times and latency comparisons across different service configurations
Message size impact: Performance analysis across different payload sizes helps you understand how message size affects overall system behavior
The following image shows the application performance metrics section of the dashboard:
Getting started
This section walks you through setting up and deploying the workbench in your AWS environment. You will configure the necessary prerequisites, deploy the infrastructure using AWS CDK, and customize your first test.
Prerequisites
You can deploy the solution from the GitHub Repo. You can clone it and run it on your AWS environment. To deploy the artifacts, you will require:
AWS account with administrative credentials configured for creating AWS resources.
Node.js version 20.9 or higher is required, with version 22+ recommended.
Docker engine must be installed and running locally as the CDK builds container images during deployment. Docker daemon should be running and accessible to CDK for building the workbench application containers.
Deployment
# Clone the workbench repository
git clone https://github.com/aws-samples/sample-simulation-workbench-for-msk-express-brokers.git

# Install dependencies and build
npm install
npm run build

# Bootstrap CDK (first time only per account/region)
cd cdk
npx cdk bootstrap

# Synthesize CloudFormation template (optional verification step)
npx cdk synth

# Deploy to AWS (creates infrastructure and builds containers)
npx cdk deploy
After deployment is completed, you will receive a CloudWatch dashboard URL to monitor the workbench performance in real-time.You can also deploy multiple isolated instances of the workbench in the same AWS account for different teams, environments, or testing scenarios. Each instance operates independently with its own MSK cluster, ECS services, and CloudWatch dashboards.To deploy additional instances, modify the Environment Configuration in cdk/lib/config.ts:
Each combination of AppPrefix and EnvPrefix creates completely isolated AWS resources so that multiple teams or environments can use the workbench simultaneously without conflicts.
Customizing your first test
You can edit the configuration file located at folder “cdk/lib/config-types.ts” to define your testing scenarios and run the deployment. It is preconfigured with the following configuration:
Following a structured approach to benchmarking ensures that your results are reliable and actionable. These best practices will help you isolate performance variables and build a clear understanding of how each configuration change affects your system’s behavior. Begin with single-service configurations to establish baseline performance:
This approach helps you understand the impact of specific configuration changes.
Important considerations and limitations
Before relying on workbench results for production decisions, it is important to understand the tool’s intended scope and boundaries. The following considerations will help you set appropriate expectations and make the most effective use of the workbench in your planning process.
Performance testing disclaimer
The workbench is designed as an educational and sizing estimation tool to help teams prepare for MSK Express production deployments. While it provides valuable insights into performance characteristics:
Results can vary based on your specific use cases, network conditions, and configurations
Use workbench results as guidance for initial sizing and planning
Conduct comprehensive performance validation with your actual workloads in production-like environments before final deployment
Recommended usage approach
Production readiness training – Use the workbench to prepare teams for MSK Express capabilities and operations.
Architecture validation – Test streaming architectures and performance expectations using MSK Express enhanced performance characteristics.
Capacity planning – Use MSK Express streamlined sizing approach (throughput-based rather than storage-based) for initial estimates.
Team preparation – Build confidence and expertise with production Apache Kafka implementations using MSK Express.
Conclusion
In this post, we showed how the workload simulation workbench for Amazon MSK Express Broker supports learning and preparation for production deployments through configurable, hands-on testing and experiments. You can use the workbench to validate configurations, build expertise, and improve performance before production deployment. If you’re preparing for your first Apache Kafka deployment, training a team, or improving existing architectures, the workbench provides practical experience and insights needed for success. Refer to Amazon MSK documentation – Complete MSK Express documentation, best practices, and sizing guidance for more information.
Organizations use streaming applications to process and analyze data in real time and adopt the Amazon MSK Connect feature of Amazon Managed Streaming for Apache Kafka (Amazon MSK) to run fully managed Kafka Connect workloads on AWS. Message brokers like Apache Kafka allow applications to handle large volumes and diverse types of data efficiently and enable timely decision-making and instant insights. It’s crucial to monitor the performance and health of each component to help ensure the seamless operation of data streaming pipelines.
Amazon MSK is a fully managed service that simplifies the deployment and operation of Apache Kafka clusters on AWS. It simplifies building and running applications that use Apache Kafka to process streaming data. Amazon MSK Connect simplifies the deployment, monitoring, and automatic scaling of connectors that transfer data between Apache Kafka clusters and external systems such as databases, file systems, and search indices. Amazon MSK Connect is fully compatible with Kafka Connect and supports Amazon MSK, Apache Kafka, and Apache Kafka compatible clusters. Amazon MSK Connect uses a custom plugin as the container for connector implementation logic.
Custom MSK connect plugins use Java Management Extensions (JMX) to expose runtime metrics. While Amazon MSK Connect sends a set of connect metrics to Amazon CloudWatch, it currently does not support exporting the JMX metrics emitted by the connector plugins natively. These metrics can be exported by modifying the custom connect plugin code directly, but it requires maintenance overhead because the plugin code needs to be modified every time it’s updated. In this post, we demonstrate an optimal approach by extending a custom connect plugin with additional modules to export JMX metrics and publish them to CloudWatch as custom metrics. These additional JMX metrics emitted by the custom connectors provide rich insights into their performance and health of the connectors. In this post, we demonstrate how you can export the JMX metrics for Debezium connector when used with MSK Connect.
Understanding JMX
Before we dive deep into exporting JMX metrics, let’s understand how JMX works. JMX is a technology that you can use to monitor and manage Java applications. Key components involved in JMX monitoring are:
Managed beans (MBeans) are Java objects that represent the metrics of the Java application being monitored. They contain the actual data points of the resources being monitored.
JMX server creates and registers the MBeans with the PlatformMBeanServer. The Java application that is being monitored acts as the JMX server and exposes the MBeans.
MBeanServer or JMX registry is the central registry that keeps track of all the registered MBeans in the JMX server. It is the access point for all the MBeans within the Java virtual machine (JVM).
JMXConnectorServer acts as a bridge between the JMX client and the JMX server and enables remote access to the exposed MBeans. JMXConnectorServerFactory creates and manages the JMXConnectorServer. It allows for the customization of the server’s properties and uses the JMXServiceURL to define the endpoint where the JMX client can connect to the JMX server.
JMXServiceURL provides the necessary information such as the protocol, host, and port for the client to connect to the JMX server and access the desired MBeans.
JMX client is an external application or tool that connect to the JMX server to access and monitor the exposed metrics.
JMX monitoring involves the steps shown in the following figure:
JMX monitoring steps include:
The Java application acting as the JMX server creates and configures MBeans for the desired metrics.
JMX server registers the MBeans with the JMX registry.
JMXConnectorServerFactory creates the JMXConnectorServer that defines the JMXServiceURL that provides the entry point details for the JMX client.
JMXClient connects to the JMX registry in the JMX server using the JMXServiceURL and the JMXConnectorServer.
The JMX server handles client requests, interacting with the JMX registry to retrieve the MBean data.
Solution overview
This method of wrapping supported Kafka connectors with custom code that exposes connector-specific operational metrics enables teams to get better insights by correlating various connector metrics with cloud-centered metrics in monitoring systems such as Amazon CloudWatch. This approach enables consistent monitoring across different components of the change data capture (CDC) pipeline, ultimately feeding metrics into unified dashboards while respecting each connector’s architectural philosophy. The consolidated metrics can be delivered to CloudWatch or the monitoring tool of your choice including partner specific application performance management (APM) tools such as Datadog, New Relic, and so on.
We have the working implementation of this same approach with two popular connectors: Debezium source connector and MongoDB Sink Connector. You can find the Github sample and ready to use plugins built for each in the repository. Review the README file for this custom implementation for more details.
For example, our custom implementation for the MongoDB Sink Connector adds a metrics export layer that calculates critical performance indicators such as latest-kafka-time-difference-ms – which measures the latency between Kafka message timestamps and connector processing time by subtracting the connector’s current clock time from the last received record’s timestamp. This custom wrapper around the MongoDB Sink Connector enables exporting relevant JMX metrics and publishing them as custom metrics to CloudWatch. We’ve open sourced this solution on GitHub, along with a ready-to-use plugin and detailed configuration guidance in the README.
CDC is the process of identifying and capturing changes made in a database and delivering those changes in real time to a downstream system. Debezium is an open source distributed platform built on top of Apache Kafka that provides CDC functionality. It provides a set of connectors to track and stream changes from databases to Kafka.
In the next section, we dive deep into the implementation details of how to export JMX metrics from Debezium MySQL Connector deployed as a custom plugin in Amazon MSK Connect. The connector plugin takes care of creating and configuring the MBeans and registering them with the JMX registry.
The following diagram shows the workflow of using Debezium MySQL Connector as a custom plugin in Amazon MSK Connect for CDC from an Amazon Aurora MySQL-Compatible Edition data source.
MySQL binary log (binlog) is enabled in Amazon Aurora for MySQL to record all the operations in the order in which they are committed to the database.
The Debezium connector plugin component of the MSK Connect custom plugin continuously monitors the MySQL database, captures the row-level changes by reading the MySQL bin logs, and streams them as change events to Kafka topics in Amazon MSK.
We’ll build a custom module to enable JMX monitoring on the Debezium connector. This module will act as a JMX client to retrieve the JMX metrics from the connector and publish them as custom metrics to CloudWatch.
The Debezium connector provides three types of metrics in addition to the built-in support for default Kafka and Kafka Connect JMX metrics.
Snapshot metrics provide information about connector operation while performing a snapshot.
Streaming metrics provide information about connector operation when the connector is reading the binlog.
Schema history metrics provide information about the status of the connector’s schema history.
In this solution, we export the MilliSecondsBehindSource streaming metrics emitted by the Debezium MySQL connector. This metricprovides the number of milliseconds that the connector is lagging behind the change events in the database.
Prerequisites
Following are the prerequisites you need:
Access to the AWS account where you want to set up this solution.
You have set up the source database and MSK cluster by following this setup instructions in the MSK Connect workshop.
Create a custom plugin
Creating a custom plugin for Amazon MSK Connect for the solution involves the following steps:
Create a custom module: Create a new Maven module or project that will contain your custom code to:
Enable JMX monitoring in the connector application by starting the JMX server.
Create a Remote Method Invocation (RMI) registry to enable the access to the JMX metrics to the clients.
Create a JMX metrics exporter to query the JMX metrics by connecting to the JMX server and push the metrics to CloudWatch as custom metrics.
Schedule to run the JMX metrics exporter at a configured interval.
Package and deploy the custom module as an MSK Connect custom plugin.
Create a connector using the custom plugin to capture CDC from the source, stream it and validate the metrics in Amazon CloudWatch.
This custom module extends the connector functionality to export the JMX metrics without requiring any changes in the underlying connector implementation. This helps ensure that upgrading the custom plugin requires only upgrading the plugin version in the pom.xml of the custom module.
Let’s deep dive and understand the implementation of each step mentioned above.
1. Create a custom module
Create a new Maven project with dependencies on Debezium MySQL Connector to enable JMX monitoring, Kafka Connect API for configuration, and CloudWatch AWS SDK to push the metrics to CloudWatch. Set up a JMX connector server to enable JMX monitoring: To enable JMX monitoring, the JMX server needs to be started at the time of initializing the connector. This is usually done by setting the environment variables with JMX options as described in Monitoring Debezium. In the case of an Amazon MSK Connect custom plugin, JMX monitoring is enabled programmatically at the time of connector plugin initialization. To achieve this:
Extend the MySqlConnector class and override the start which is the connector’s entry point to execute custom code.
public class DebeziumMySqlMetricsConnector extends MySqlConnector{
@Override
	public void start(Map<String, String> props) {
In the start method of the custom connector class (DebeziumMySqlMetricsConnector) that we are creating, set the following parameters to allow customization of the JMX Server properties by retrieving connector configuration from a config file.
connect.jmx.port – The port number on which the RMI registry needs to be created. JMXConnectorServer would listen to the incoming connections on this port.
database.server.name – Name of the database that is the source for the CDC.
It also retrieves the CloudWatch configuration related properties that will be used while pushing the JMX metrics to CloudWatch.
cloudwatch.namespace.name – CloudWatch NameSpace to which the metrics need to be pushed as custom metrics
cloudwatch.region – CloudWatch Region where the custom namespace is created in your AWS account
Create an RMI registry on the specified port (connectJMXPort). This registry is used by the JMXConnectorServer to store the RMI objects corresponding to the MBeans in the JMX registry. This allows the JMX clients to look up and access the MBeans on the PlatformMBeanServer.
LocateRegistry.createRegistry(connectJMXPort);
Retrieve the PlatformMBeanServer and construct the JMXServiceURL which is in the format service:jmx:rmi://localhost/jndi/rmi://localhost:<<jmx.port>>/jmxrmi. Create a new JMXConnectorServer instance using the JMXConnectorServerFactory and the JMXServiceURL and start the JMXConnectorServer instance.
Implement JMX metrics exporter: Create a JMX client to connect to the JMX server, query the MilliSecondBehindSource metric from the JMX server, convert it into the required format, and export it to CloudWatch.
Connect to the JMX Server using the JMXConnectorFactory and JMXServiceURL
Query the MBean object that holds the corresponding metric, for example, MilliSecondsBehindSource, and retrieve the metric value using sample code provided in msk-connect-custom-plugin-jmx. (you can choose one or more metrics).
Schedule the execution of your JMX metrics exporter at regular intervals.
Export metrics to CloudWatch: Implement the logic to push relevant JMX metrics to CloudWatch. You can use the AWS SDK for Java to interact with the CloudWatch PutMetricData API or use the CloudWatch Logs subscription filter to ingest the metrics from a dedicated Kafka topic.
For more information, see the sample implementation for the custom module in aws-samples in GitHub. This sample also provides custom plugins packaged with two different versions of Debezium MySQL connector (debezium-connector-mysql-2.5.2.Final-plugin and debezium-connector-mysql-2.7.3.Final-plugin) and the following steps would explain the steps to build a custom plugin using your custom code.
2. Package the custom module and Debezium MySQL connector as a custom plugin
Build and package the Maven project with the custom code as a JAR file and include the JAR file in the debezium-connector-mysql-2.5.2.Final-plugin folder downloaded from maven repo. Package the updated debezium-connector-mysql-2.5.2.Final-plugin as a ZIP file (Amazon MSK Connect accepts custom plugins in ZIP or JAR format). Alternatively, you can use the prebuiltcustom-debezium-mysql-connector-plugin.zip available in GitHub.
Choose the Debezium connector version (2.5 or 2.7) that fits your requirement.
When you have to upgrade to a new version of the Debezium MySQL connector, you can update the version of the dependency and build the custom module and deploy it. By doing this, you can maintain the custom plugin without modifying the original connector code. The GitHub samples provide ready-to-use plugins for two Debezium connector versions. However, you can follow the same approach to upgrade to the latest connector version as well.
Create a custom plugin in Amazon MSK
If you have set up your AWS resources by following the Getting Started lab, open Amazon S3 console and locate the bucket msk-lab-${ACCOUNT_ID}-plugins-bucket/debezium .
Upload the custom plugin created in the previous section custom-debezium-mysql-connector-plugin.zip to msk-lab-${ACCOUNT_ID}-plugins-bucket/debezium, as shown in the following figure.
Switch to the Amazon MSK console and choose Custom plugins in the navigation pane. Choose Create custom plugin and, browse the S3 bucket that you created above and select the custom plugin ZIP file you just uploaded.
Enter custom-debezium-mysql-connector-plugin for the plugin name. Optionally, enter a description and choose Create Custom Plugin.
After a few seconds you should see the plugin is created and the status is Active.
Customize the worker configuration for the connector by following the instructions in the Customize worker configuration lab.
3. Create an Amazon MSK connector
The next step is to create an MSK connector.
From the MSK section choose Connectors, then choose Create connector. Choose custom-debezium-mysql-connector-plugin from the list of Custom plugins, then choose Next.
Enter custom-debezium-mysql-connector in the Name textbox, and a description for the connector.
Select the MSKCluster-msk-connect-lab from the listed MSK clusters. From the Authentication dropdown, select IAM.
Copy the following configuration and paste it in the connector configuration textbox.
Replace the <Your Aurora MySQL database endpoint>, <Your Database Password>, <Your MSK Bootstrap Server Address>, and <Your CloudWatch Region>placeholders with the corresponding details for the resources in your account.
Review the topic.prefix, database.user, topic.prefix, database.server.id, database.server.name, database.port, database.include.listparameters in the configuration. These parameters are configured with the values used in the workshop. Update them with the details corresponding to your configuration if you have customized it in your account.
Note that the connector.classparameter is updated with the qualified name of the subclass of MySqlConnector class that you created in the custom module.
The connect.jmx.portparameter specifies the default port to start the JMX server. You can configure this to any available port.
5. Follow the remaining instructions from the Create MSK Connector lab and create the connector. Verify that the connector status changes to Running.
Debezium MySQL custom connector version (2.7.3) provides additional flexibility to configure optional properties that can be added to your MSK connector configuration and selectively include and exclude metrics to emit to CloudWatch. The following are the example configuration properties that can be used with version 2.7.3 :
cloudwatch.debezium.streaming.metrics.include – A comma-separated list of streaming metrics type that must be exported to CloudWatch as custom metrics.
cloudwatch.debezium.streaming.metrics.exclude – Specify a comma-separated list of streaming metrics types to exclude from being sent to CloudWatch as custom metrics.
Similarly include and exclude properties for snapshot metrics type are cloudwatch.debezium.snapshot.metrics.include and cloudwatch.debezium.snapshot.metrics.exclude
Include and exclude properties for schema history metrics type are cloudwatch.debezium.schema.history.metrics.include and cloudwatch.debezium.schema.history.metrics.exclude
Review the GitHub README file for more details on the use of these properties with MSK connector configurations.
Verify the replication in the Kafka cluster and CloudWatch metrics
Follow the instructions in the Verify the replication in the Kafka cluster lab to set up a client and make changes to the source DB and verify that the changes are captured and sent to Kafka topics by the connector.
To verify that the connector has published the JMX metrics to CloudWatch, go to the CloudWatch console and choose Metrics in the navigation pane, then choose All Metrics. Under Custom namespace, you can see MSK_Connect with database name as the dimension. Select the database name to view the metrics.
Select the MilliSecondBehindSource metric with statistic as Average in the Graphed Metric to plot the graph. You can verify that the MilliSecondBehindSource metric value is greater than zero whenever any operation is being performed on the source database and returns to zero during the idle time.
Clean up
Delete the resources that you created such as the Aurora DB, Amazon MSK Cluster and connectors by following the instructions at Cleanup in the Amazon MSK Connect lab if you have been following along to set up the solution on your account.
Conclusion
In this post, we showed you how to extend the Debezium MySQL connector plugin with an additional module to export the JMX metrics to CloudWatch as custom metrics. As a next step, you can create a CloudWatch alarm to monitor the metrics and take remediation actions when the alarm is triggered. In addition to exporting the JMX metrics to CloudWatch, you can export these metrics to third-party applications such as Prometheus or DataDog using CloudWatch Metric Streams. You can follow a similar approach to export the JMX metrics of other connectors from MSK Connect. You can learn more about creating your own connectors by visiting the Connector Developer Guide and how to deploy them as custom plugins in the MSK Connect documentation.
About the authors
Jaydev Nath is a Solutions Architect at AWS, where he works with ISV customers to build secure, scalable, reliable, and cost-efficient cloud solutions. He brings strong expertise in building SaaS architecture on AWS with a focus on Generative AI and data analytics technologies to help deliver practical, valuable business outcomes for customers.
David John Chakram is a Principal Solutions Architect at AWS. He specializes in building data platforms and architecting seamless data ecosystems. With a profound passion for databases, data analytics, and machine learning, he excels at transforming complex data challenges into innovative solutions and driving businesses forward with data-driven insights.
Sharmila Shanmugam is a Solutions Architect at Amazon Web Services. She is passionate about solving the customers’ business challenges with technology and automation and reduce the operational overhead. In her current role, she helps customers across industries in their digital transformation journey and build secure, scalable, performant and optimized workloads on AWS.
As organizations build modern applications with event-driven architectures (EDA), they often seek solutions that minimize infrastructure management overhead while maximizing developer productivity. Amazon Managed Streaming for Apache Kafka (Amazon MSK) and AWS Lambda together provide a serverless, scalable, and cost-efficient platform for real-time event-driven processing.
In this post, we describe how you can simplify your event-driven application architecture using AWS Lambda with Amazon MSK. We demonstrate how to configure Lambda as a consumer for Kafka topics, including a cross-account setup and how to optimize price and performance for these applications.
Why use Lambda with Amazon MSK?
Customers building event-driven applications have several key priorities when it comes to their architecture choices. They typically seek to reduce their operational overhead by using Amazon Web Services (AWS) to handle the complex, underlying infrastructure components so their teams can focus on core business logic. Additionally, developers prefer a streamlined experience that minimizes the need for repetitive boilerplate code, enabling them to be more productive and focus on creating value. Furthermore, these customers want to achieve both scalability and cost-effectiveness without the burden of managing compute infrastructure directly. Lambda integration with Amazon MSK effectively addresses these requirements, delivering a comprehensive solution that combines the benefits of serverless computing with managed Kafka services. For example, an ecommerce company can use Amazon MSK to collect real-time clickstream data from its website and process those events using AWS Lambda. With this integration, they can trigger Lambda functions to update recommendation models, send personalized offers, or analyze user behavior instantly—without provisioning or managing servers. The key benefits of using Lambda with Amazon MSK include:
Simplicity through native integration – AWS Lambda offers native integration with Amazon MSK through a connector resource called event source mapping. You can use this integration to directly associate a Kafka topic—whether it’s on Amazon MSK or a self-managed Kafka cluster—as an event source for a Lambda function without writing custom consumer logic. With just a few configuration steps, event source mapping handles partition assignment, offset tracking, and parallelized batch processing under the hood. It uses the Kafka consumer group protocol to distribute topic partitions across multiple concurrent Lambda invocations, supports batch windowing, and enables at-least-once delivery semantics. Moreover, it automatically commits offsets upon successful function execution while handling retries and dead-letter queue (DLQ) routing for failed records, significantly reducing the operational overhead traditionally associated with Kafka consumers.
Auto scaling and throughput controls – When using AWS Lambda with Amazon MSK through event source mapping, Lambda automatically scales by assigning a dedicated event poller per Kafka partition, enabling parallel, partition-based processing. This allows the system to elastically handle varying traffic without manual intervention. For advanced control, provisioned concurrency pre-initializes Lambda execution environments, eliminating cold starts and delivering consistent low-latency performance. Additionally, with provisioned event source mapping, you can configure the minimum and maximum number of Kafka pollers, providing precise control over throughput and concurrency. This is ideal for applications with unpredictable traffic patterns or strict latency requirements.
Cost-effectiveness – AWS Lambda uses a pay-per-use model in which you only pay for compute time and number of invocations. When integrated with Amazon MSK, there are no charges for idle time, making it ideal for bursty or low-frequency Kafka workloads. You can further optimize costs by tuning batch size and batch window settings. For mission-critical workloads, provisioned concurrency provides consistent performance with controlled pricing.
Event filtering – AWS Lambda supports event filtering for Amazon MSK event sources, which means you can process only the Kafka records that match specific criteria. This reduces unnecessary function invocations and optimizes your function costs. You can define up to five filters per event source mapping (with the option to request an increase to ten). Each filter uses a JSON-based pattern to specify the conditions a record must meet to be processed. Filters can be applied using the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS Serverless Application Model (AWS SAM) templates. For more details and examples, refer to the AWS Lambda documentation on event filtering with Amazon MSK.
Handling Availability Zone outage for your consumer – Amazon MSK enables high availability for your Kafka brokers by distributing them across multiple Availability Zones within a Region. To maintain high availability across your application, you similarly need a consumer that offers high availability. AWS Lambda offers high availability and resilience by running your consumer functions across multiple Availability Zones in a Region. This means that even if one Availability Zone experiences an outage, your Lambda function will continue to operate in other healthy Availability Zones. While Lambda manages security patching and Availability Zone failure scenarios, you can focus on your application logic.
Cross-account event processing – Cross-account connectivity between AWS Lambda and Amazon MSK allows a Lambda function in one AWS account to consume data from an MSK cluster in another account using MSK multi-VPC private connectivity powered by AWS PrivateLink. This setup is particularly beneficial for organizations that centralize Kafka infrastructure while maintaining separate accounts for different applications or teams.
Support for JSON, Avro, Protobuf, and Schema Registries – AWS Lambda supports Kafka events in JSON, Avro and Protobuf formats via event source mapping. It integrates with AWS Glue Schema registry, Confluent Cloud Schema registry, and self-managed Confluent Schema registry , enabling native schema validation, filtering, and deserialization without custom code.
How Lambda processes messages from your Kafka topic
Lambda uses event source mappings to process records from Amazon MSK by actively polling Kafka topics through event pollers that invoke Lambda functions with batches of records. These mappings are Lambda managed resources designed for high-throughput, stream-based processing. By default, Lambda detects the OffsetLag for all partitions in your Kafka topic and automatically scales pollers based on traffic. For high-throughput applications, you can enable provisioned mode to define minimum and maximum pollers, and your event source mapping auto scales between the minimum and maximum defined values. In the provisioned mode, each poller can process up to 5 MBps and supports concurrent Lambda invocations.
After Lambda processes each batch, it commits the offsets of the messages in that batch. If your function returns an error for a message in a batch, Lambda retries the whole batch of messages until processing succeeds or the messages expire. You can send records that fail all retry attempts to an on-failure destination for later processing. To maintain ordered processing within a partition, Lambda limits the maximum event pollers to the number of partitions in the topic. When setting up Kafka as a Lambda event source, you can specify a consumer group ID to let Lambda join an existing Kafka consumer group. If other consumers are active in that group, Lambda will receive only part of the topic’s messages. If the group exists, Lambda starts from the group’s committed offset, ignoring the StartingPosition. The following diagram illustrates this flow.
Walkthrough: Build a serverless Kafka app with AWS Lambda
Follow these steps to build a serverless application that consumes messages from an MSK cluster using AWS Lambda:
Create an Amazon MSK cluster. Use the AWS Management Console or AWS CLI to create your MSK cluster. When the cluster is up, create your Kafka topic(s). For detailed instructions, refer to the Amazon MSK documentation.
Create a Lambda function using the AWS Management Console or the AWS CLI. To learn more about creating a Lambda function, refer to Create your first Lambda function. The Lambda function’s execution role needs to have the following permissions:
Access to connect to your MSK cluster
Permissions to manage elastic network interfaces in your VPC
To connect Lambda to Amazon MSK as a consumer, set up event source mapping to link your MSK topic with the Lambda function. This allows Lambda to automatically poll for new messages and process them. Follow the guide on how to configure event source mapping.
For reference, configuring event source mapping involves three steps:
Network setup – In the default event source mapping mode, you need to configure a networking setup using a PrivateLink endpoint or NAT gateway for event source mapping to invoke Lambda functions. In provisioned mode, no networking configuration is needed (and you don’t incur the cost of networking components).
Event source mapping parameter configuration – This involves setting necessary configuration parameters for the event source mapping to be able to poll messages from your Kafka cluster. This includes the MSK cluster, topic name, consumer group ID, authentication method, and optionally, schema registry, scaling mode. You can configure the scaling mode for provisioned throughput, along with batch size, batch window, and event filtering for your event source mapping.
Access permissions – This involves configuring required permissions to access the required AWS resources, and includes configuring permissions for the function to execute the code, permissions for the event source mapping to access your MSK cluster, and permissions for Lambda to access your VPC resources.
The following screenshot shows the console setup for configuring Amazon MSK event source mapping, including the Amazon MSK trigger related fields.
The following screenshot shows event poller configuration.
The following screenshot shows additional settings you can use, depending on your use case.
Optimizing AWS Lambda for stream processing with Amazon MSK
When building real-time data processing pipelines with Amazon MSK and AWS Lambda, it’s important to tune your setup for both performance and cost-efficiency. Lambda offers powerful serverless compute capabilities, but to get the most out of it in a streaming context, you need to make a few key optimizations:
Enable provisioned concurrency for low-latency processing – For workloads that are sensitive to latency—cold starts can introduce unwanted delays. By enabling provisioned concurrency, you can pre-warm a specified number of Lambda instances so they’re always ready to handle traffic immediately. This eliminates cold starts and provides consistent response times, which is crucial for latency-critical use cases.
Enable provisioned mode for event source mapping for high-throughput processing – For Kafka workloads with stringent throughput requirements, activate the provisioned mode. The optimal configuration of minimum and maximum event pollers for your Kafka event source mapping depends on your application’s performance requirements. Start with the default minimum event pollers to baseline the performance profile and adjust event pollers based on observed message processing patterns and your application’s performance requirements. For workloads with spiky traffic and strict performance needs, increase the minimum event pollers to handle sudden surges. You can fine-tune the minimum event pollers by evaluating your desired throughput, your observed throughput, which depends on factors such as the ingested messages per second and average payload size, and using the throughput capacity of one event poller (up to 5 MB/s) as reference. To maintain ordered processing within a partition, Lambda caps the maximum event pollers at the number of partitions in the topic.
Optimize message batching using size and windowing – By integrating Lambda with Amazon MSK, you can control how messages are batched before they’re sent to your function. Tuning parameters such as batch size (the number of records per invocation: 1–10,000 records) and maximum batching window (how long to wait for a full batch: 0–300 seconds) can significantly impact performance. Larger batches mean fewer invocations, which reduces overhead and improves throughput. However, it’s important to strike a balance—too large a batch or window might introduce unwanted processing delays. Monitor your stream’s behavior and adjust these settings based on throughput requirements and acceptable latency.
Apply filters to reduce unnecessary invocations – Not every record in your Kafka topic might require processing. To avoid unnecessary Lambda invocations (and associated costs), apply filtering logic directly when configuring the event source mapping. With Lambda, you can define filtering (up to 10 filters) criteria so that only relevant records trigger your function. This helps reduce compute time, minimize noise, and optimize your budget, especially when dealing with high-throughput topics with mixed content. For Amazon MSK, Lambda commits offsets for matched and unmatched messages after successfully invoking the function.
Conclusion
By combining Amazon MSK with AWS Lambda, you can seamlessly build modern, serverless event-driven applications. This integration eliminates the need to manage consumer groups, compute infrastructure, or scaling logic so teams can focus on delivering business value faster.
Whether you’re integrating Kafka into microservices, transforming data pipelines, or building reactive applications, Lambda with Amazon MSK is a powerful and flexible serverless solution. For detailed documentation on how to configure Lambda with Amazon MSK, refer to the AWS Lambda Developer Guide. For more serverless learning resources, visit Serverless Land.
About the Authors
Tarun Rai Madan is a Principal Product Manager at Amazon Web Services (AWS). He specializes in serverless technologies and leads product strategy to help customers achieve accelerated business outcomes with event-driven applications, using services like AWS Lambda, AWS Step Functions, Apache Kafka, and Amazon SQS/SNS. Prior to AWS, he was an engineering leader in the semiconductor industry, and led development of high-performance processors for wireless, automotive, and data center applications.
Masudur Rahaman Sayem is a Streaming Data Architect at AWS with over 25 years of experience in the IT industry. He collaborates with AWS customers worldwide to architect and implement sophisticated data streaming solutions that address complex business challenges. As an expert in distributed computing, Sayem specializes in designing large-scale distributed systems architecture for maximum performance and scalability. He has a keen interest and passion for distributed architecture, which he applies to designing enterprise-grade solutions at internet scale.
Managing and scaling data streams efficiently is a cornerstone of success for many organizations. Apache Kafka has emerged as a leading platform for real-time data streaming, offering unmatched scalability and reliability. However, setting up and scaling Kafka clusters can be challenging, requiring significant time, expertise, and resources. This is where Amazon Managed Streaming for Apache Kafka (Amazon MSK) Express brokers come into play.
Express brokers are a new broker type in Amazon MSK that are designed to simplify Kafka deployment and scaling.
In this post, we walk you through the implementation of MSK Express brokers, highlighting their core features, benefits, and best practices for rapid Kafka scaling.
Key features of MSK Express brokers
MSK Express brokers revolutionize Kafka cluster management by delivering exceptional performance and operational simplicity. With up to three times more throughput per broker, Express brokers can sustainably handle an impressive 500 MBps ingress and 1000 MBps egress on m7g.16xl instances, setting new standards for data streaming performance.
Their standout feature is their fast scaling capability—up to 20 times faster than standard Kafka brokers—allowing rapid cluster expansion within minutes. This is complemented by 90% faster recovery from failures and built-in three-way replication, providing robust reliability for mission-critical applications.
Express brokers eliminate traditional storage management responsibility by offering unlimited storage without pre-provisioning, while simplifying operations through preconfigured best practices and automated cluster management. With full compatibility with existing Kafka APIs and comprehensive monitoring through Amazon CloudWatch and Prometheus, MSK Express brokers provide an ideal solution for organizations seeking a highly-performant and low-maintenance data streaming infrastructure.
Comparison with traditional Kafka deployment
Although Kafka provides robust fault-tolerance mechanisms, its traditional architecture, where brokers store data locally on attached storage volumes, can lead to several issues impacting the availability and resiliency of the cluster. The following diagram compares the deployment architecture.
The traditional architecture comes with the following limitations:
Extended recovery times – When a broker fails, recovery requires copying data from surviving replicas to the newly assigned broker. This replication process can be time-consuming, particularly for high-throughput workloads or in cases where recovery requires a new volume, resulting in extended recovery periods and reduced system availability.
Suboptimal load distribution – Kafka achieves load balancing by redistributing partitions across brokers. However, this rebalancing operation can strain system resources and take considerable time due to the volume of data that must be transferred between nodes.
Complex scaling operations – Expanding a Kafka cluster requires adding brokers and redistributing existing partitions across the new nodes. For large clusters with substantial data volumes, this scaling operation can impact performance and require significant time to complete.
MSK Express brokers offers fully managed and highly available Regional Kafka storage. This significantly decouples compute and storage resources, addressing the aforementioned challenges and improving the availability and resiliency of Kafka clusters. The benefits include:
Faster and more reliable broker recovery – When Express brokers recover, they do so in up to 90% less time than standard brokers and place negligible strain on the clusters’ resources, which makes recovery faster and more reliable.
Efficient load balancing – Load balancing in MSK Express brokers is faster and less resource-intensive, enabling more frequent and seamless load balancing operations.
Faster scaling – MSK Express brokers enable efficient cluster scaling through rapid broker addition, minimizing data transfer overhead and partition rebalancing time. New brokers become operational quickly due to accelerated catch-up processes, resulting in faster throughput improvements and minimal disruption during scaling operations.
Scaling use case example
Consider a use case requiring 300 MBps data ingestion on a Kafka topic. We implemented this using an MSK cluster with three m7g.4xlarge Express brokers. The configuration included a topic with 3,000 partitions and 24-hour data retention, with each broker initially managing 1,000 partitions.
To prepare for anticipated midday peak traffic, we needed to double the cluster capacity. This scenario highlights one of Express brokers’ key advantages: rapid, safe scaling without disrupting application traffic or requiring extensive advance planning. During this scenario, the cluster was actively handling approximately 300 MBps of ingestion. The following graph shows the total ingress on this cluster and the number of partitions it is holding across three brokers.
The scaling process involved two main steps:
Adding three additional brokers to the cluster, which completed in approximately 18 minutes
Using Cruise Control to redistribute the 3,000 partitions evenly across all six brokers, which took about 10 minutes
As shown in the following graph, the scaling operation completed smoothly, with partition rebalancing occurring rapidly across all six brokers while maintaining uninterrupted producer traffic.
Notably, throughout the entire process, we observed no disruption to producer traffic. The entire operation to double the cluster’s capacity was completed in just 28 minutes, demonstrating MSK Express brokers’ ability to scale efficiently with minimal impact on ongoing operations.
Best practices
Consider the following guidelines to adopt MSK Express brokers:
When implementing new streaming workloads on Kafka, select MSK Express brokers as your default option. If uncertain about your workload requirements, begin with express.m7g.large instances.
Use the Amazon MSK sizing tool to calculate optimal broker count and type for your workload. Although this provides a good baseline, always validate through load testing that simulates your real-world usage patterns.
Choose larger instance types for high-throughput workloads. A smaller number of large instances is preferable to many smaller instances, because fewer total brokers can simplify cluster management operations and reduce operational overhead.
Conclusion
MSK Express brokers represent a significant advancement in Kafka deployment and management, offering a compelling solution for organizations seeking to modernize their data streaming infrastructure. Through its innovative architecture that decouples compute and storage, MSK Express brokers deliver simplified operations, superior performance, and rapid scaling capabilities.
The key advantages demonstrated throughout this post—including 3 times higher throughput, 20 times faster scaling, and 90% faster recovery times—make MSK Express brokers an attractive option for both new Kafka implementations and migrations from traditional deployments.
As organizations continue to face growing demands for real-time data processing, MSK Express brokers provide a future-proof solution that combines the reliability of Kafka with the operational simplicity of a fully managed service.
Masudur Rahaman Sayem is a Streaming Data Architect at AWS with over 25 years of experience in the IT industry. He collaborates with AWS customers worldwide to architect and implement sophisticated data streaming solutions that address complex business challenges. As an expert in distributed computing, Sayem specializes in designing large-scale distributed systems architecture for maximum performance and scalability. He has a keen interest and passion for distributed architecture, which he applies to designing enterprise-grade solutions at internet scale.
Data loses value over time. We hear from our customers that they’d like to analyze the business transactions in real time. Traditionally, customers used batch-based approaches for data movement from operational systems to analytical systems. Batch load can run once or several times a day. A batch-based approach can introduce latency in data movement and reduce the value of data for analytics. Change Data Capture (CDC)-based approach has emerged as alternative to batch-based approaches. A CDC-based approach captures the data changes and makes them available in data warehouses for further analytics in real-time.
CDC tracks changes made in source database, such as inserts, updates, and deletes, and continually updates those changes to target database. When the CDC is high-frequency, the source database is changing rapidly, and the target database (i.e., usually a data warehouse) needs to reflect those changes in near real-time.
With the explosion of data, the number of data systems in organizations has grown. Data silos causes data to live in different sources, which makes it difficult to perform analytics.
To gain deeper and richer insights, you can bring all the changes from different data silos into one place, like data warehouse. This post showcases how to use streaming ingestion to bring data to Amazon Redshift.
Redshift streaming ingestion provides low latency, high-throughput data ingestion, which enables customers to derive insights in seconds instead of minutes. It’s simple to set up, and directly ingests streaming data into your data warehouse from Amazon Kinesis Data Streams and Amazon Managed Streaming for Kafka (Amazon MSK) without the need to stage in Amazon Simple Storage Service (Amazon S3). You can create materialized views using SQL statements. After that, using materialized-view refresh, you can ingest hundreds of megabytes of data per second.
Solution overview
In this post, we create a low-latency data replication between Amazon Aurora MySQL to Amazon Redshift Data Warehouse, using Redshift streaming ingestion from Amazon MSK. Using Amazon MSK, we securely stream data with a fully managed, highly available Apache Kafka service. Apache Kafka is an open-source distributed event streaming platform used by thousands of companies for high-performance data pipelines, streaming analytics, data integration, and mission-critical applications. We store CDC events in Amazon MSK, for a set duration of time, which makes it possible to deliver CDC events to additional destinations such as Amazon S3 data lake.
We deploy Debezium MySQL source Kafka connector on Amazon MSK Connect. Amazon MSK Connect makes it easy to deploy, monitor, and automatically scale connectors that move data between Apache Kafka clusters and external systems such as databases, file systems, and search indices. Amazon MSK Connect is a fully compatible with Apache Kafka Connect, which enables you to lift and shift your Apache Kafka Connect applications with zero code changes.
This solution uses Amazon Aurora MySQL hosting the example database salesdb. Users of the database can perform the row-level INSERT, UPDATE, and DELETE operations to produce the change events in the example salesdb database. Debezium MySQL source Kafka Connector reads these change events and emits them to the Kafka topics in Amazon MSK. Amazon Redshift then read the messages from the Kafka topics from Amazon MSK using Amazon Redshift Streaming feature. Amazon Redshift stores these messages using materialized views and process them as they arrive.
You can see how CDC performs create event by looking at this example here. We are going to use OP field – its mandatory string describes the type of operation that caused the connector to generate the event, in our solution for processing. In this example, c indicates that the operation created a row. Valid values for OP field are:
c = create
u = update
d = delete
r = read (applies to only snapshots)
The following diagram illustrates the solution architecture:
The solution workflow consists of the following steps:
Amazon Aurora MySQL has a binary log (i.e., binlog) that records all operations(INSERT, UPDATE, DELETE) in the order in which they are committed to the database.
Amazon MSK Connect runs the source Kafka Connector called Debezium connector for MySQL, reads the binlog, produces change events for row-level INSERT, UPDATE, and DELETE operations, and emits the change events to Kafka topics in amazon MSK.
An Amazon Redshift-provisioned cluster is the stream consumer and can read messages from Kafka topics from Amazon MSK.
A materialized view in Amazon Redshift is the landing area for data read from the stream, which is processed as it arrives.
When the materialized view is refreshed, Amazon Redshift compute nodes allocate a group of Kafka partition to a compute slice.
Each slice consumes data from the allocated partitions until the view reaches parity with last Offset for the Kafka topic.
Subsequent materialized view refreshes read data from the last offset of the previous refresh until it reaches parity with the topic data.
Inside the Amazon Redshift, we created stored procedure to process CDC records and update target table.
Prerequisites
This post assumes you have a running Amazon MSK Connect stack in your environment with the following components:
Aurora MySQL hosting a database. In this post, you use the example database salesdb.
The Debezium MySQL connector running on Amazon MSK Connect, which connects Amazon MSK in your Amazon Virtual Private Cloud (Amazon VPC).
You should provision the Amazon Redshift cluster in same VPC of Amazon MSK cluster. If you haven’t deployed one, then follow the steps here in the AWS Documentation.
We use AWS Identity and Access Management (AWS IAM) authentication for communication between Amazon MSK and Amazon Redshift cluster. Please make sure you have created an AWS IAM role with a trust policy that allows your Amazon Redshift cluster to assume the role. For information about how to configure the trust policy for the AWS IAM role, see Authorizing Amazon Redshift to access other AWS services on your behalf. After it’s created, the role should have the following AWS IAM policy, which provides permission for communication with the Amazon MSK cluster.
Please replace the ARN containing xxx from above example policy with your Amazon MSK cluster’s ARN.
Also, verify that Amazon Redshift cluster has access to Amazon MSK cluster. In Amazon Redshift Cluster’s security group, add the inbound rule for MSK security group allowing port 9098. To see how to manage redshift cluster security group, refer Managing VPC security groups for a cluster.
And, in the Amazon MSK cluster’s security group add the inbound rule allowing port 9098 for leader IP address of your Amazon Redshift Cluster, as shown in the following diagram. You can find the IP address for your Amazon Redshift Cluster’s leader node on properties tab of Amazon Redshift cluster from AWS Management Console.
Walkthrough
Navigate to the Amazon Redshift service from AWS Management Console, then set up Amazon Redshift streaming ingestion for Amazon MSK by performing the following steps:
Enable_case_sensitive_identifier to true – In case you are using default parameter group for Amazon Redshift Cluster, you won’t be able to set enable_case_sensitive_identifier to true. You can create new parameter group with enable_case_sensitive_identifier to true and attach it to Amazon Redshift cluster. After you modify parameter values, you must reboot any clusters that are associated with the modified parameter group. It may take few minutes for Amazon Redshift cluster to reboot.
This configuration value that determines whether name identifiers of databases, tables, and columns are case sensitive. Once done, please open a new Amazon Redshift Query Editor V2, so that config changes we made are reflected, then follow next steps.
Create an external schema that maps to the streaming data source.
CREATE EXTERNAL SCHEMA MySchema
FROM MSK
IAM_ROLE 'arn:aws:iam::YourRole:role/msk-redshift-streaming'
AUTHENTICATION IAM
CLUSTER_ARN 'arn:aws:kafka:us-east-1:2073196*****:cluster/MSKCluster-msk-connect-lab/849b47a0-65f2-439e-b181-1038ea9d4493-10'; // Replace last part with your cluster ARN, this is just for example.//
Once done, verify if you are seeing below tables created from MSK Topics:
Create a materialized view that references the external schema.
CREATE MATERIALIZED VIEW customer_debezium AUTO REFRESH YES AS
SELECT
*,
json_parse(kafka_value) as payload
from
"dev"."myschema"."salesdb.salesdb.CUSTOMER" ; // Replace myshecma with name you have given to your external schema in step 2 //
Now, you can query newly created materialized view customer_debezium using below command.
SELECT * FROM "dev"."public"."customer_debezium" order by refresh_time desc;
Check the materialized view is populated with the CDC records
REFRESH MATERIALIZED VIEW (optional). This step is optional as we have already specified AUTO REFRESH AS YES while creating MV (materialized view).
NOTE: Above the materialized view is auto-refreshed, which means if you don’t see the records immediately, then you have wait for few seconds and rerun the select statement. Amazon Redshift streaming ingestion view also comes with the option of a manual refresh, which allow you to manually refresh the object. You can use the following query that pulls streaming data to Redshift object immediately.
SELECT * FROM "dev"."public"."customer_debezium" order by refresh_time desc;
Process CDC records in Amazon Redshift
In following steps, we create the staging table to hold the CDC data, which is target table that holds the latest snapshot and stored procedure to process CDC records and update in target table.
Create staging table: The staging table is a temporary table that holds all of the data that will be used to make changes to the target table, including both updates and inserts.
CREATE TABLE public.customer_stg (
customer_id character varying(256) ENCODE raw
distkey
,
customer_name character varying(256) ENCODE lzo,
market_segment character varying(256) ENCODE lzo,
ts_ms bigint ENCODE az64,
op character varying(2) ENCODE lzo,
record_rank smallint ENCODE az64,
refresh_time timestamp without time zone ENCODE az64
) DISTSTYLE KEY
SORTKEY
(customer_id); // In this particular example, we have used LZO encoding as LZO encoding works well for CHAR and VARCHAR columns that store very long character strings. You can use BYTEDICT as well if it matches your use case. //
Create target table
We use customer_target table to load the processed CDC events.
CREATE TABLE public.customer_target (
customer_id character varying(256) ENCODE raw
distkey
,
customer_name character varying(256) ENCODE lzo,
market_segment character varying(256) ENCODE lzo,
refresh_time timestamp without time zone ENCODE az64
) DISTSTYLE KEY
SORTKEY
(customer_id);
Create Last_extract_time debezium table and Inserting Dummy value.
We need to store the timestamp of last extracted CDC events. We use of debezium_last_extract table for this purpose. For initial record we insert a dummy value, which enables us to perform a comparison between current and next CDC processing timestamp.
CREATE TABLE public.debezium_last_extract (
process_name character varying(256) ENCODE lzo,
latest_refresh_time timestamp without time zone ENCODE az64
) DISTSTYLE AUTO;

Insert into public.debezium_last_extract VALUES ('customer','1983-01-01 00:00:00');

SELECT * FROM "dev"."public"."debezium_last_extract";
Create stored procedure
This stored procedure processes the CDC records and updates the target table with the latest changes.
CREATE OR REPLACE PROCEDURE public.incremental_sync_customer()

LANGUAGE plpgsql

AS $$

DECLARE

sql VARCHAR(MAX) := '';

max_refresh_time TIMESTAMP;

staged_record_count BIGINT :=0;

BEGIN

-- Get last loaded refresh_time number from target table

sql := 'SELECT MAX(latest_refresh_time) FROM debezium_last_extract where process_name =''customer'';';

EXECUTE sql INTO max_refresh_time;

-- Truncate staging table

EXECUTE 'TRUNCATE customer_stg;';

-- Insert (and transform) latest change record for member with sequence number greater than last loaded sequence number into temp staging table

EXECUTE 'INSERT INTO customer_stg ('||

'select coalesce(payload.after."CUST_ID",payload.before."CUST_ID") ::varchar as customer_id,payload.after."NAME"::varchar as customer_name,payload.after."MKTSEGMENT" ::varchar as market_segment, payload.ts_ms::bigint,payload."op"::varchar, rank() over (partition by coalesce(payload.after."CUST_ID",payload.before."CUST_ID")::varchar order by payload.ts_ms::bigint desc) as record_rank, refresh_time from CUSTOMER_debezium where refresh_time > '''||max_refresh_time||''');';

sql := 'SELECT COUNT(*) FROM customer_stg;';

EXECUTE sql INTO staged_record_count;

RAISE INFO 'Staged member records: %', staged_record_count;

// replace customer_stg with your staging table name //

-- Delete records from target table that also exist in staging table (updated/deleted records)

EXECUTE 'DELETE FROM customer_target using customer_stg WHERE customer_target.customer_id = customer_stg.customer_id';

// replace customer_target with your target table name //

-- Insert all records from staging table into target table

EXECUTE 'INSERT INTO customer_target SELECT customer_id,customer_name, market_segment, refresh_time FROM customer_stg where record_rank =1 and op <> ''d''';

-- Insert max refresh time to control table

EXECUTE 'INSERT INTO debezium_last_extract SELECT ''customer'', max(refresh_time) from customer_target ';

END

$$
Test the solution
Update example salesdb hosted on Amazon Aurora
This will be your Amazon Aurora database and we access it from Amazon Elastic Compute Cloud (Amazon EC2) instance with Name= KafkaClientInstance.
Please replace the Amazon Aurora endpoint with value of your Amazon Aurora endpoint and execute following command and the use salesdb.
mysql -f -u master -h mask-lab-salesdb.xxxx.us-east-1.rds.amazonaws.com --password=S3cretPwd99
Do an update, insert , and delete in any of the tables created. You can also do update more than once to check the last updated record later in Amazon Redshift.
Invoke the stored procedure incremental_sync_customer created in the above steps from Amazon Redshift Query Editor v2. You can manually run proc using following command or schedule it.
call incremental_sync_customer();
Check the target table for latest changes. This step is to check latest values in target table. You’ll see that all the updates and deletes that you did in source table are shown at top as a result order by refresh_time.
SELECT * FROM "dev"."public"."customer_target" order by refresh_time desc;
Extending the solution
In this solution, we showed CDC processing for the customer table, and you can use the same approach to extend it to other tables in the example salesdb database or add more databases to MSK Connect configuration property database.include.list.
Our proposed approach can work with any MySQL source supported by Debezium MySQL source Kafka Connector. Similarly, to extend this example to your workloads and use-cases, you need to create the staging and target tables according to the schema of the source table. Then you need to update the coalesce(payload.after."CUST_ID",payload.before."CUST_ID")::varchar as customer_id statements with the column names and types in your source and target tables. Like in example stated in this post, we used LZO encoding as LZO encoding, which works well for CHAR and VARCHAR columns that store very long character strings. You can use BYTEDICT as well if it matches your use case. Another consideration to keep in mind while creating target and staging tables is choosing a distribution style and key based on data in source database. Here we have chosen distribution style as key with Customer_id, which are based on source data and schema update by following the best practices mentioned here.
In case you don’t want to delete Amazon Redshift clusters, you can manually drop MV and tables created during this post using below commands:
drop MATERIALIZED VIEW customer_debezium;
drop TABLE public.customer_stg;
drop TABLE public.customer_target;
drop TABLE public.debezium_last_extract;
Also, please remove inbound security rules added to your Amazon Redshift and Amazon MSK Clusters, along with AWS IAM roles created in the Prerequisites section.
Conclusion
In this post, we showed you how Amazon Redshift streaming ingestion provided high-throughput, low-latency ingestion of streaming data from Amazon Kinesis Data Streams and Amazon MSK into an Amazon Redshift materialized view. We increased speed and reduced cost of streaming data into Amazon Redshift by eliminating the need to use any intermediary services.
Furthermore, we also showed how CDC data can be processed rapidly after generation, using a simple SQL interface that enables customers to perform near real-time analytics on variety of data sources (e.g., Internet-of-Things [ IoT] devices, system telemetry data, or clickstream data) from a busy website or application.
As you explore the options to simplify and enable near real-time analytics for your CDC data,
We hope this post provides you with valuable guidance. We welcome any thoughts or questions in the comments section.
About the Authors
Umesh Chaudhari is a Streaming Solutions Architect at AWS. He works with AWS customers to design and build real time data processing systems. He has 13 years of working experience in software engineering including architecting, designing, and developing data analytics systems.
Vishal Khatri is a Sr. Technical Account Manager and Analytics specialist at AWS. Vishal works with State and Local Government helping educate and share best practices with customers by leading and owning the development and delivery of technical content while designing end-to-end customer solutions.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.
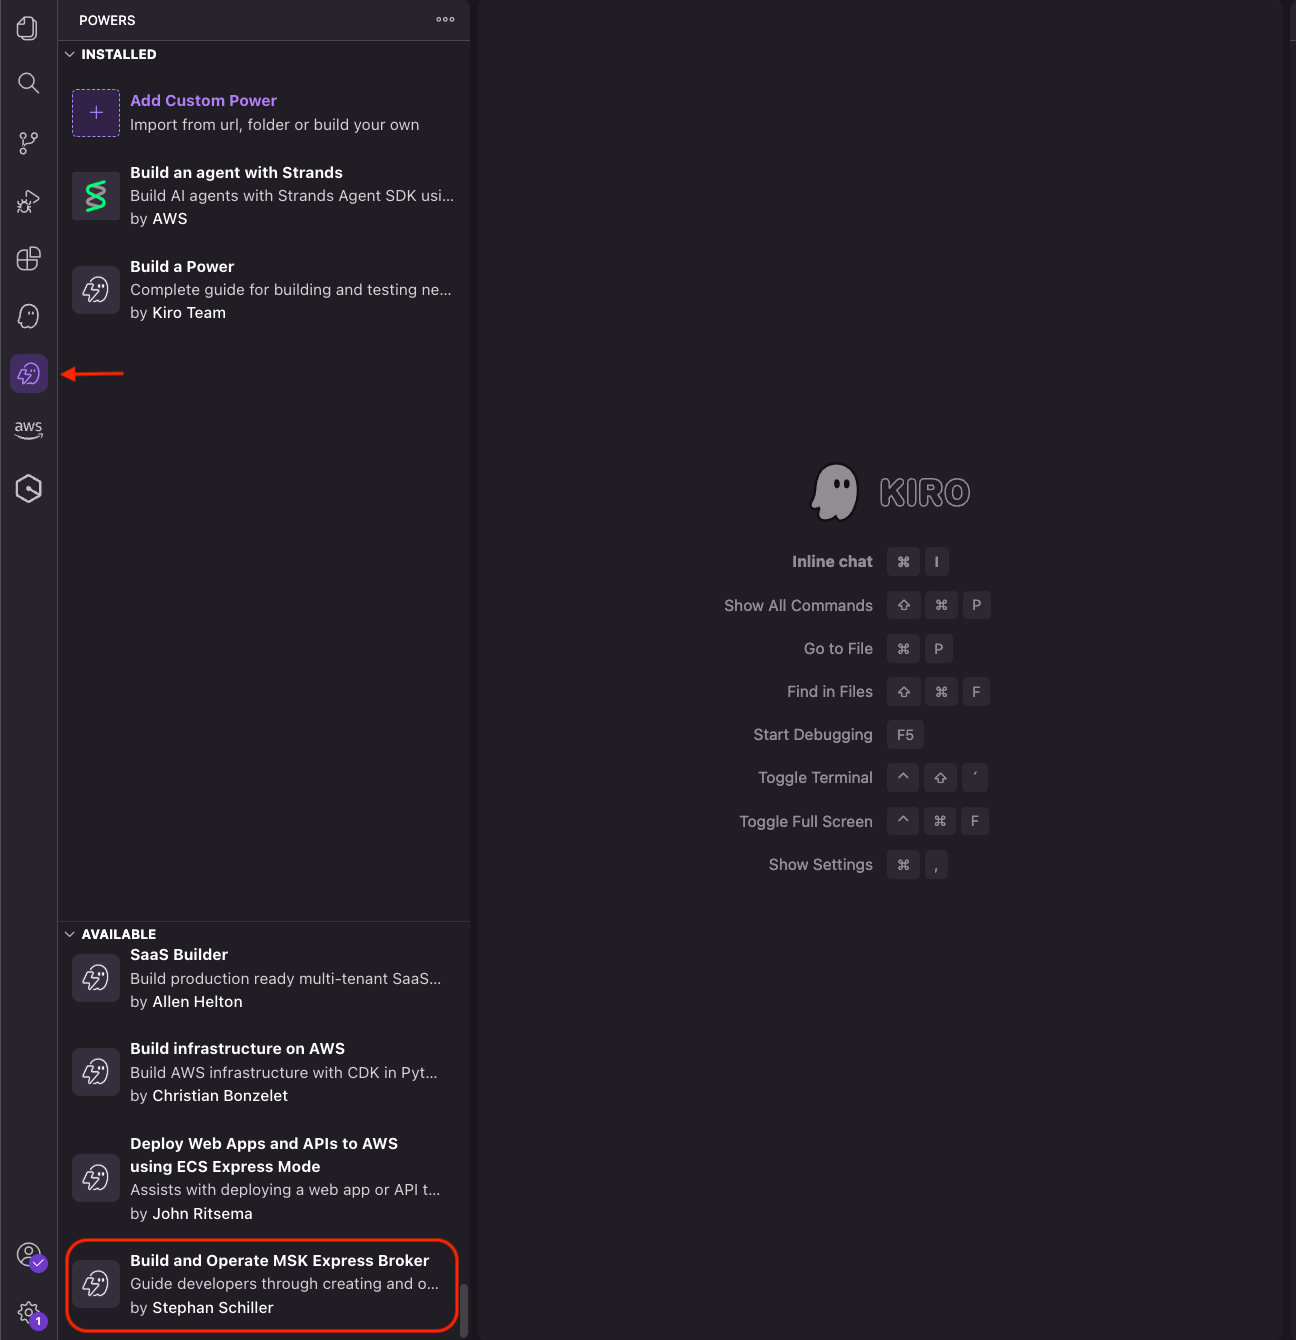
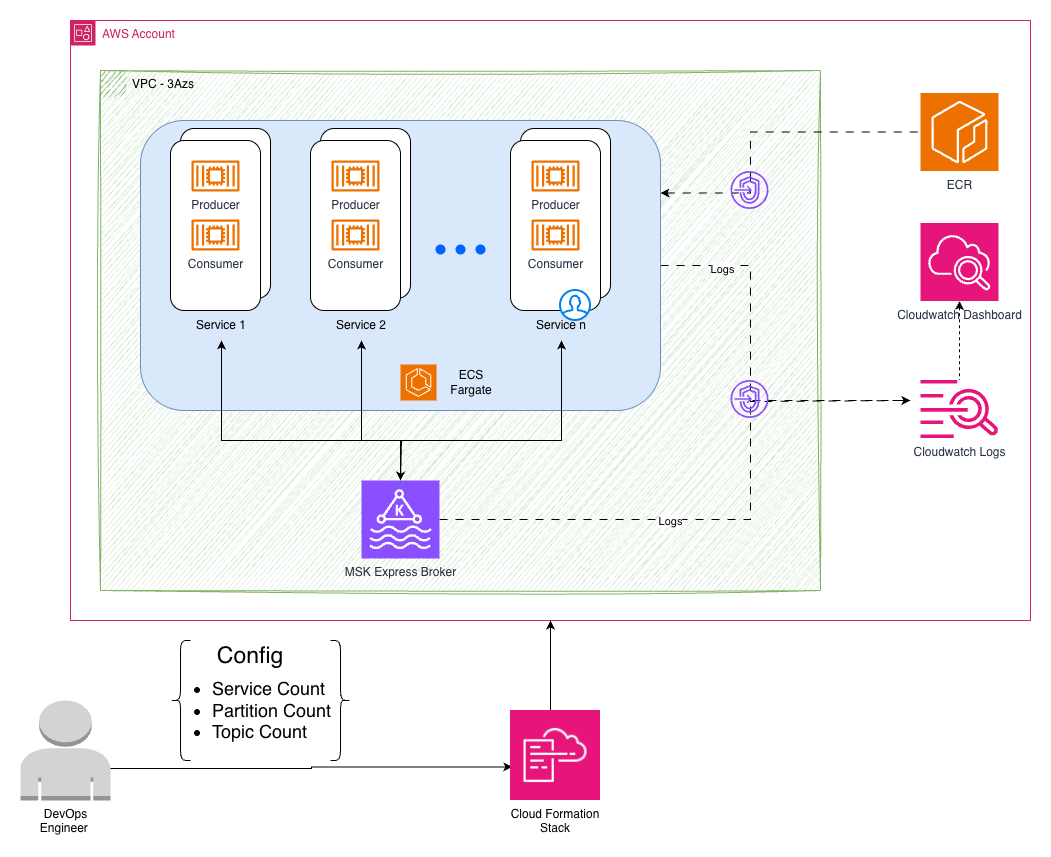
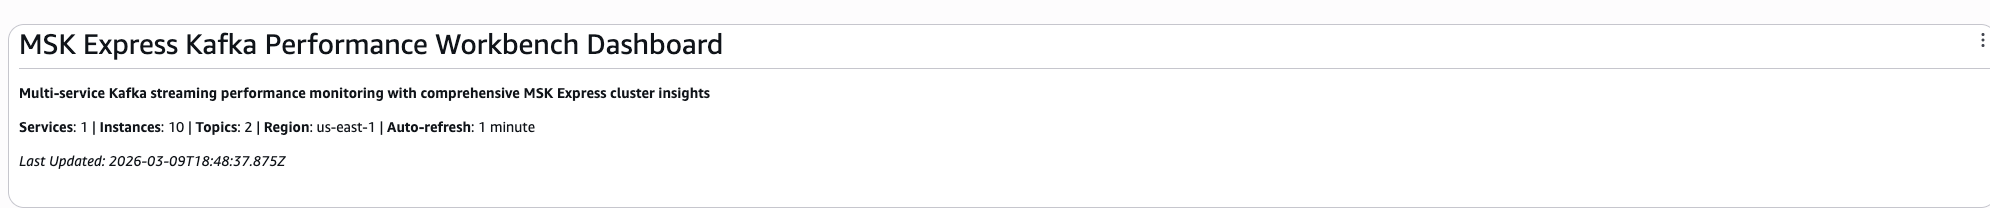
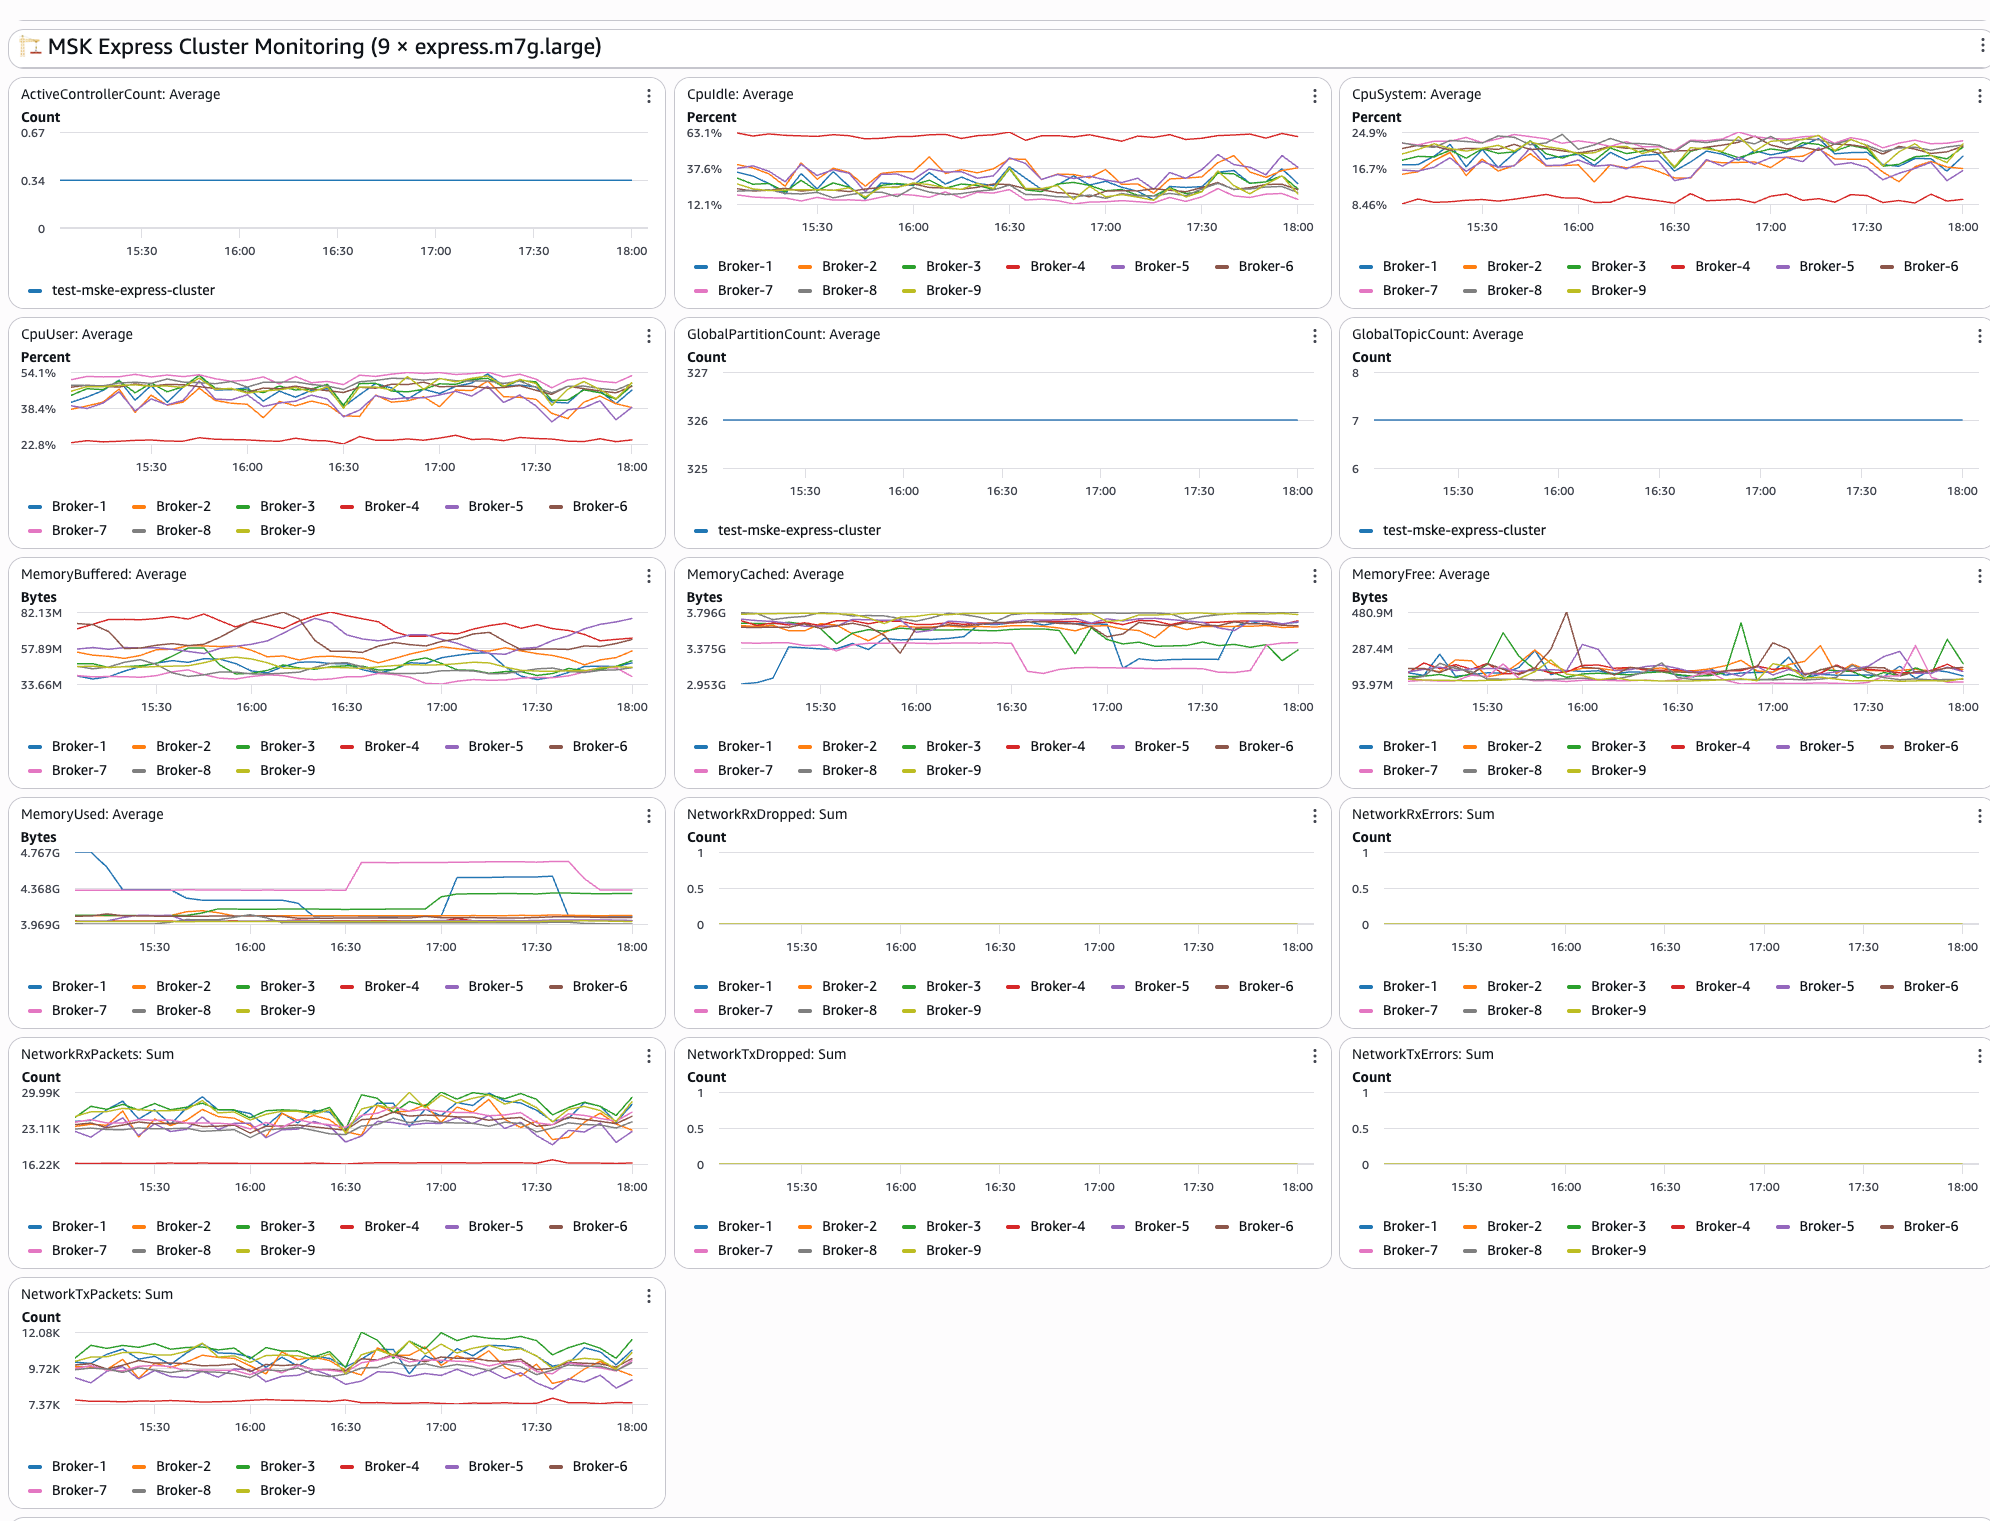
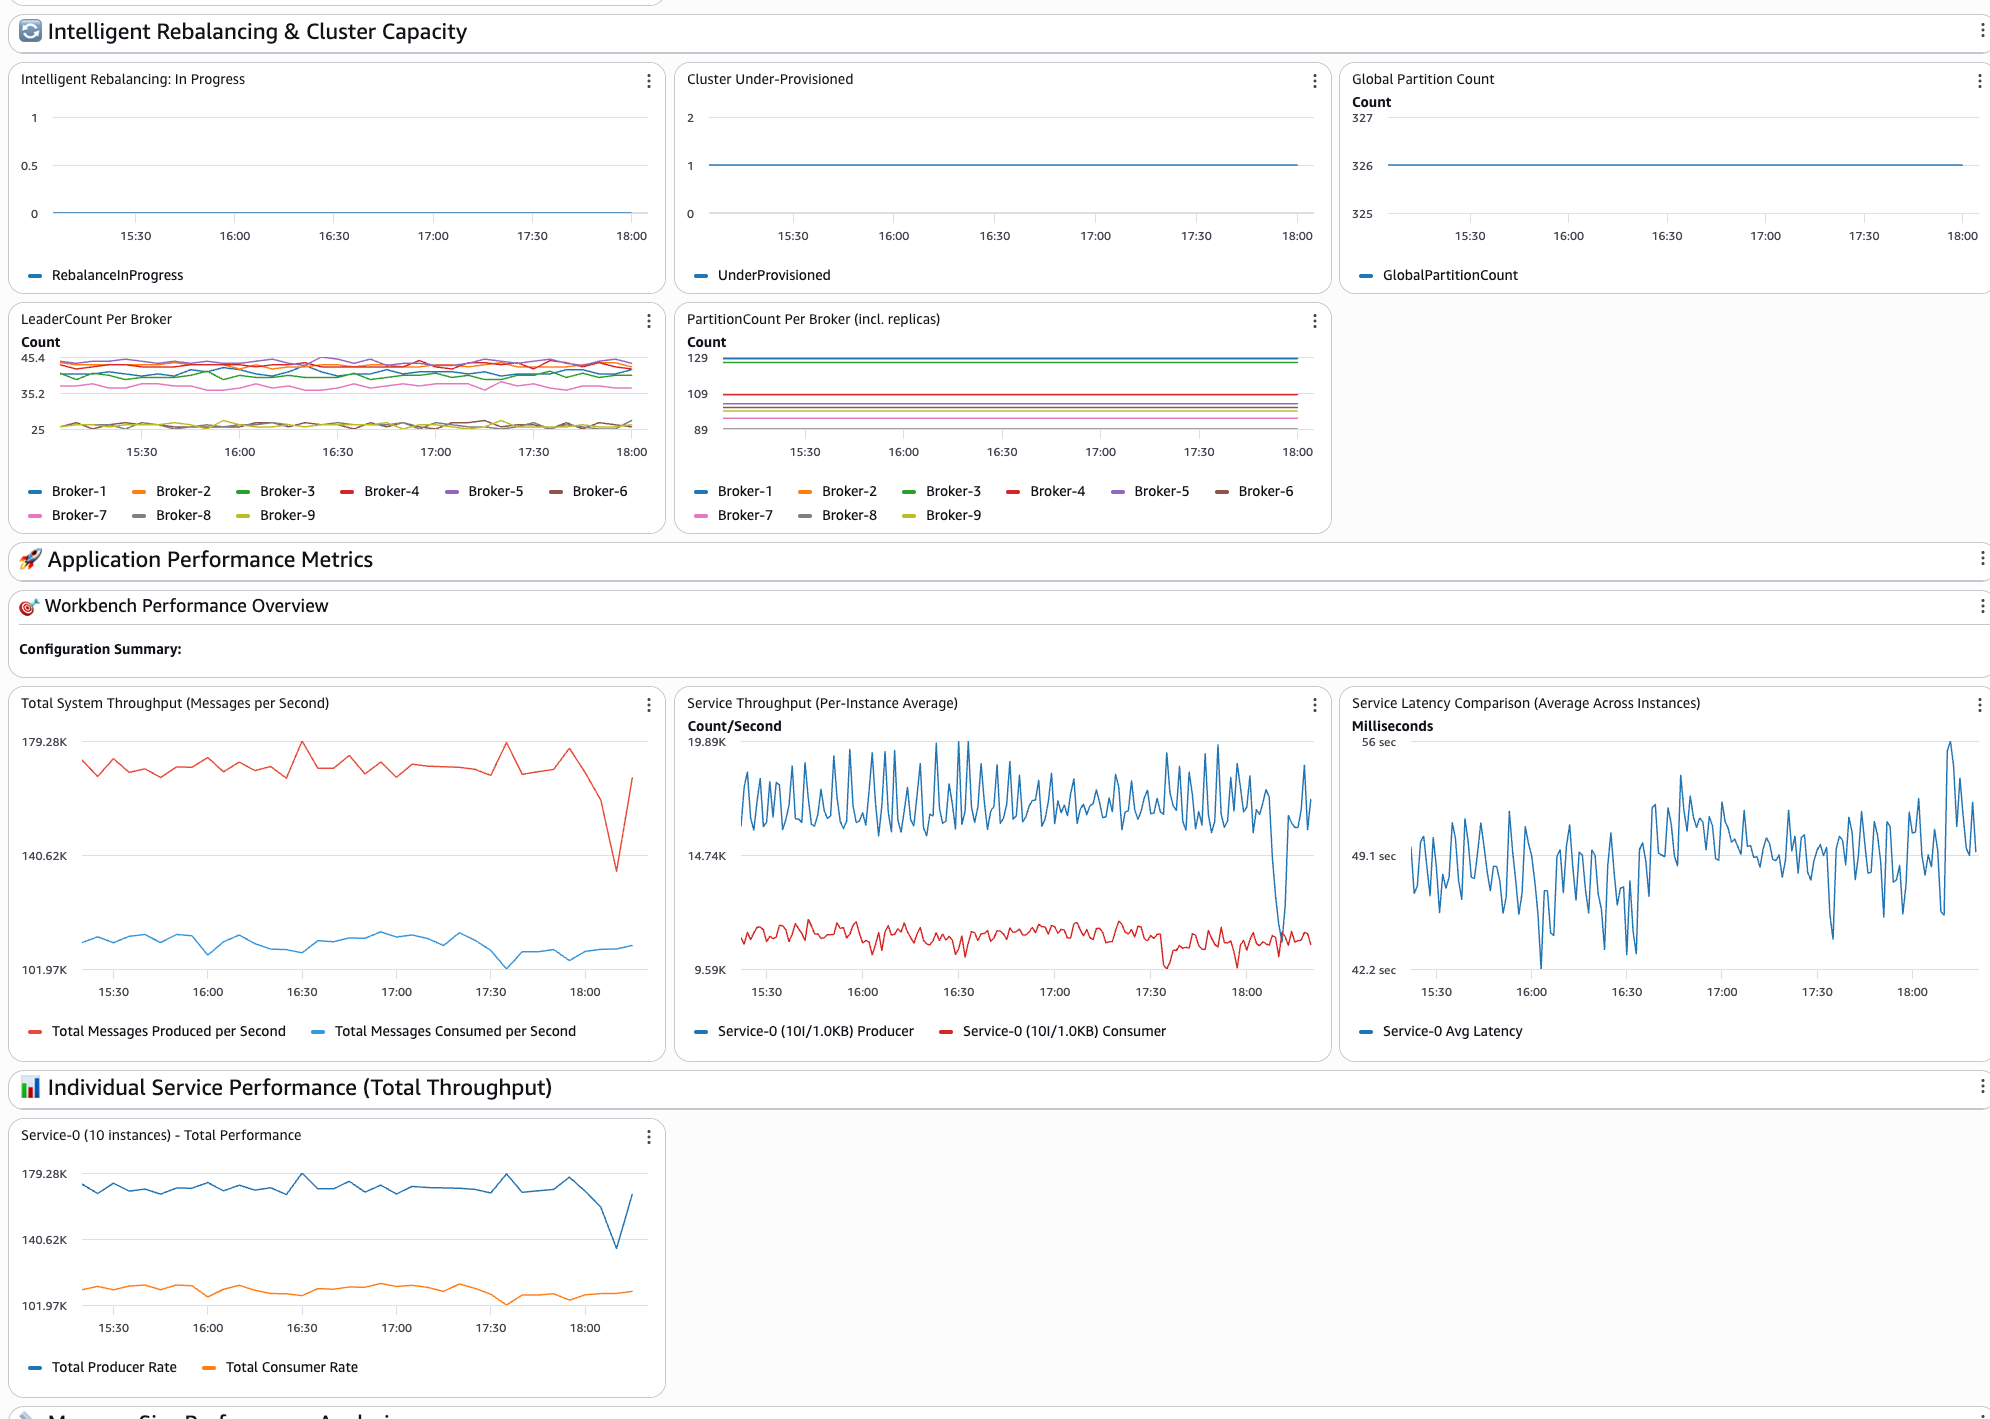
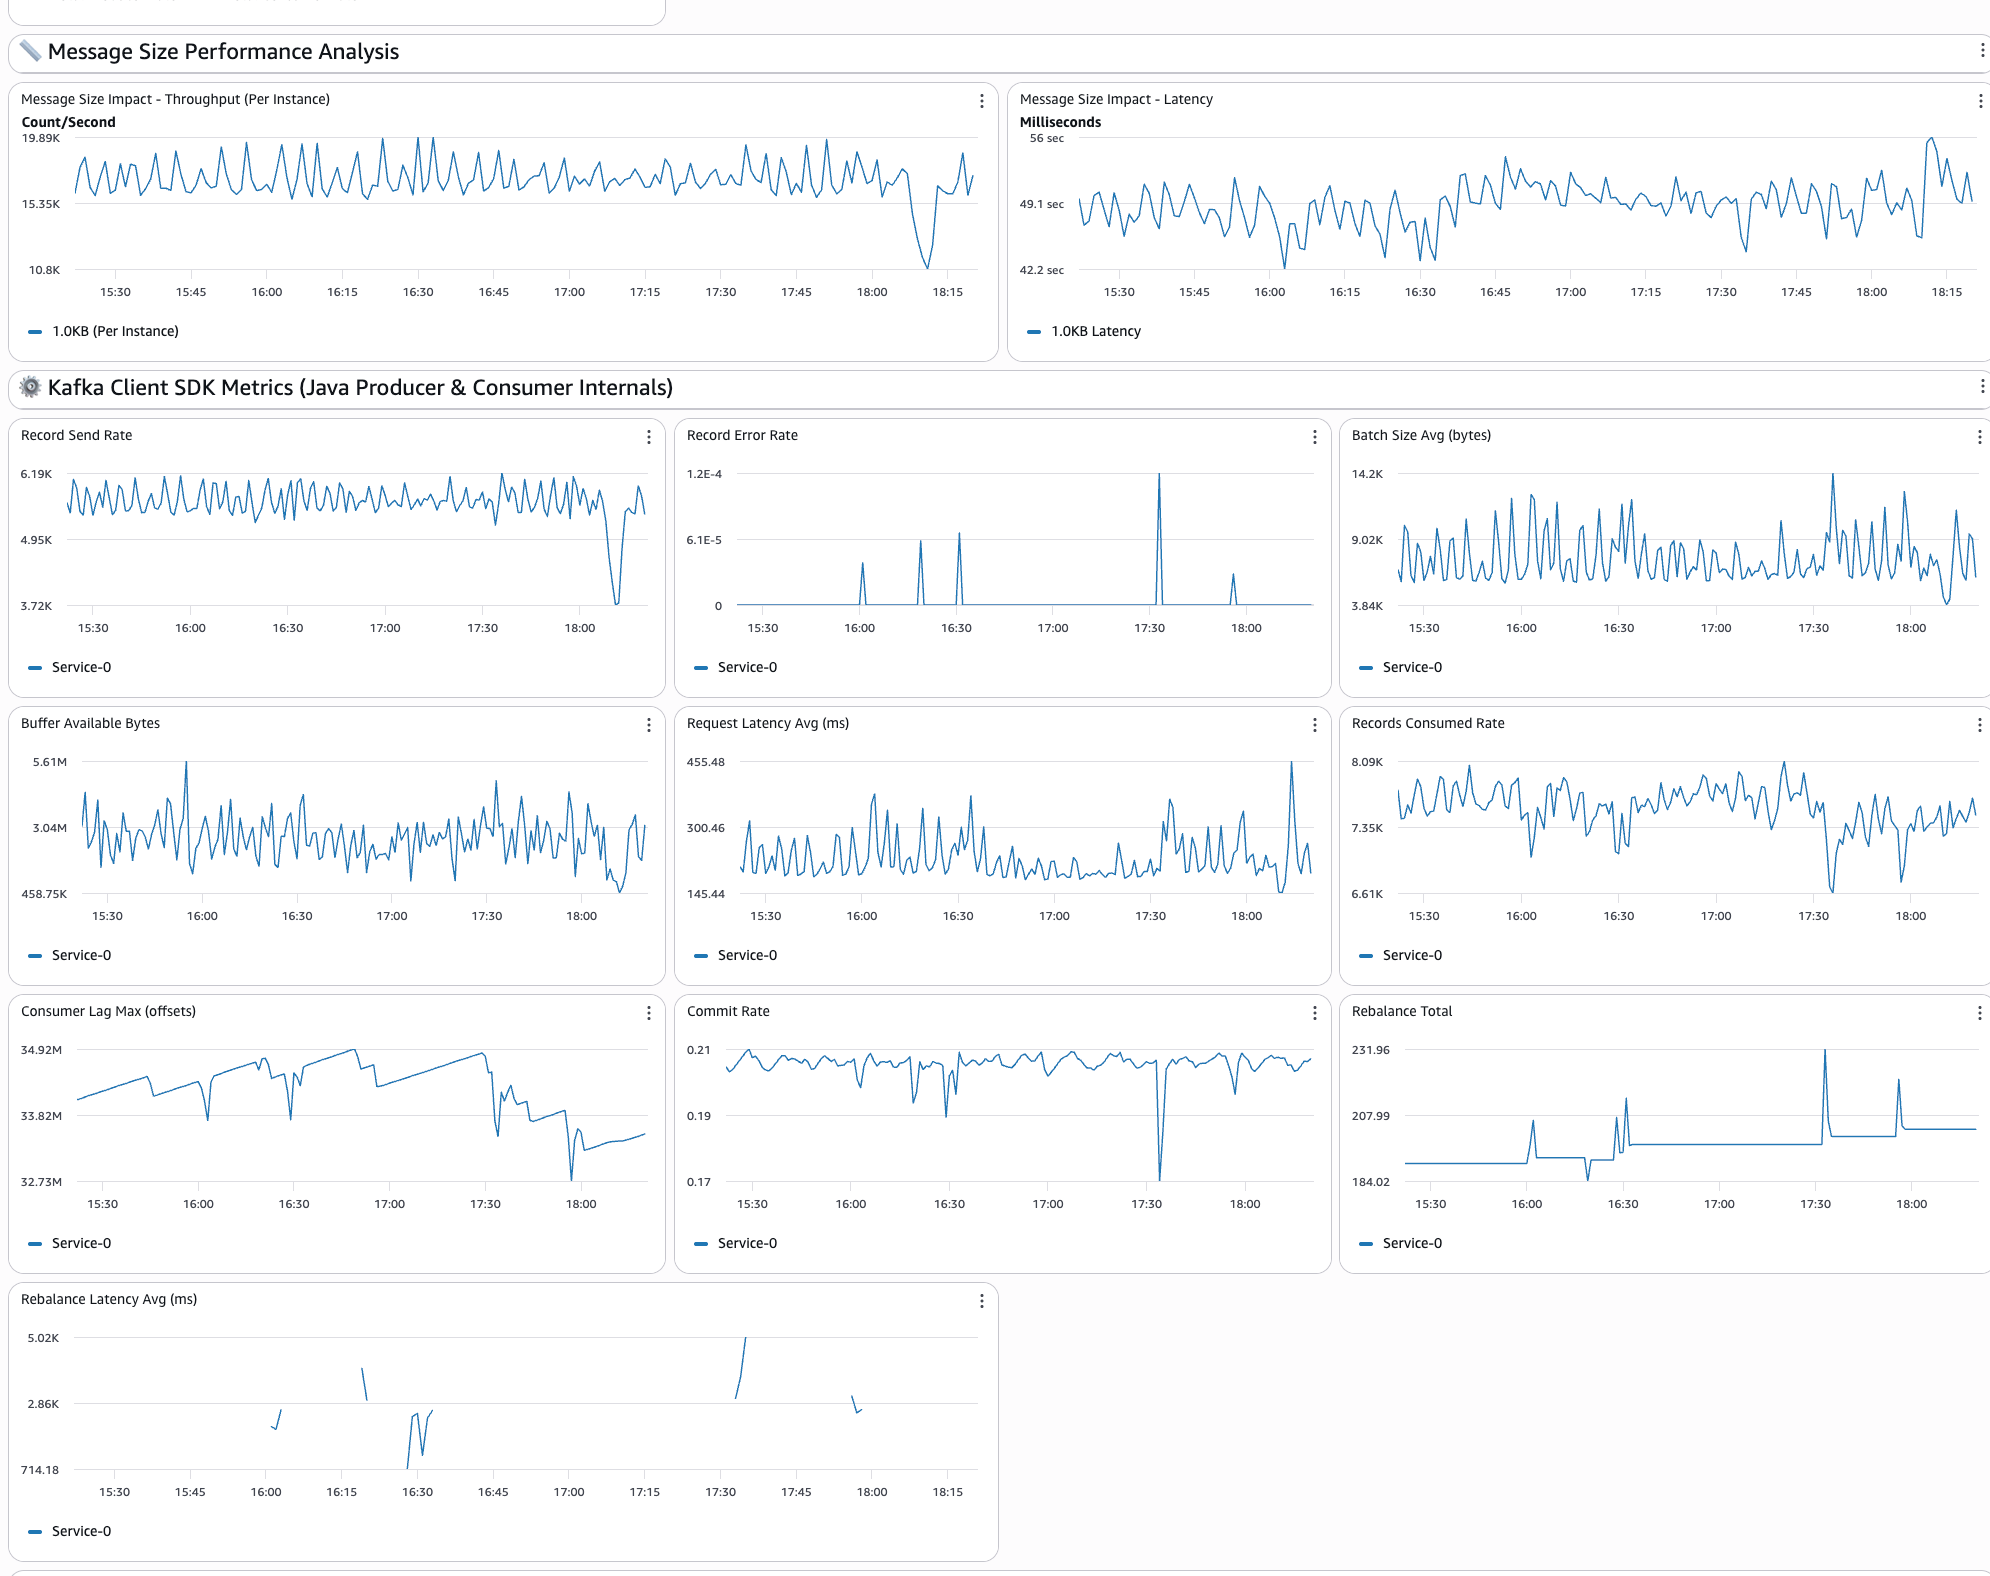
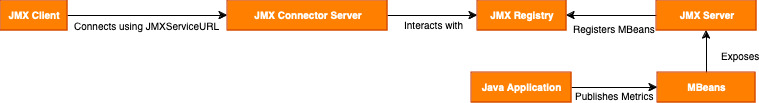
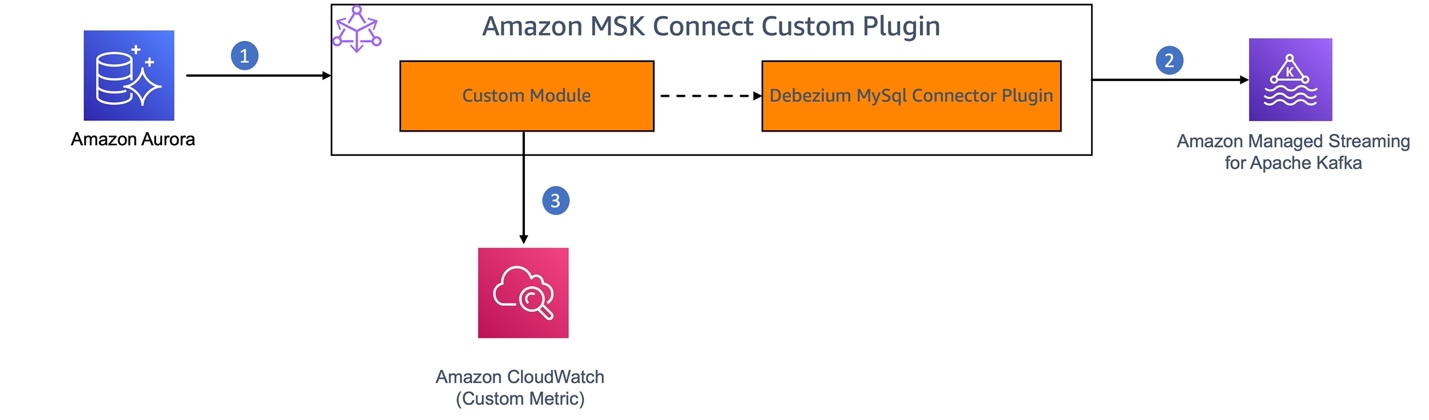
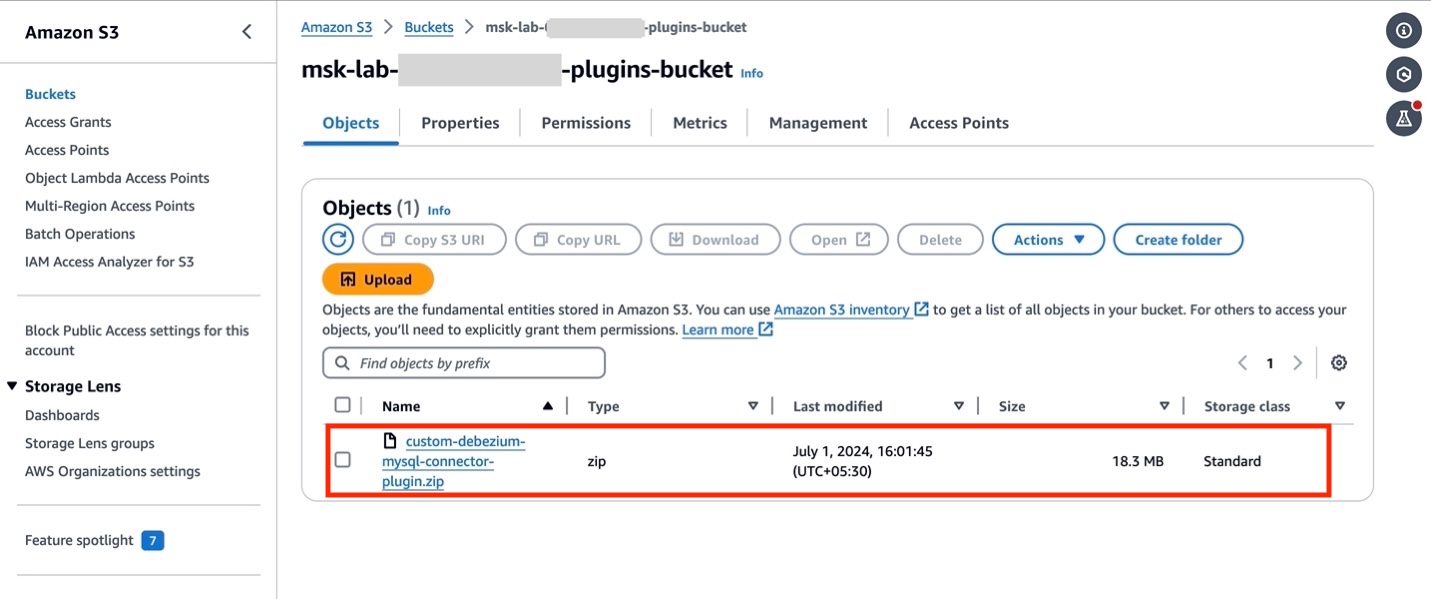
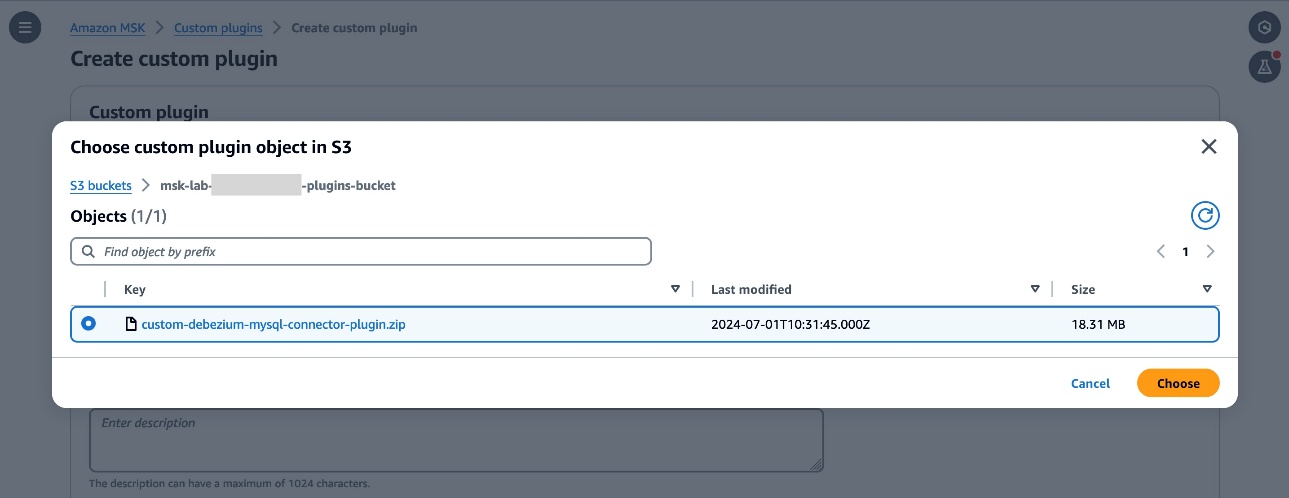
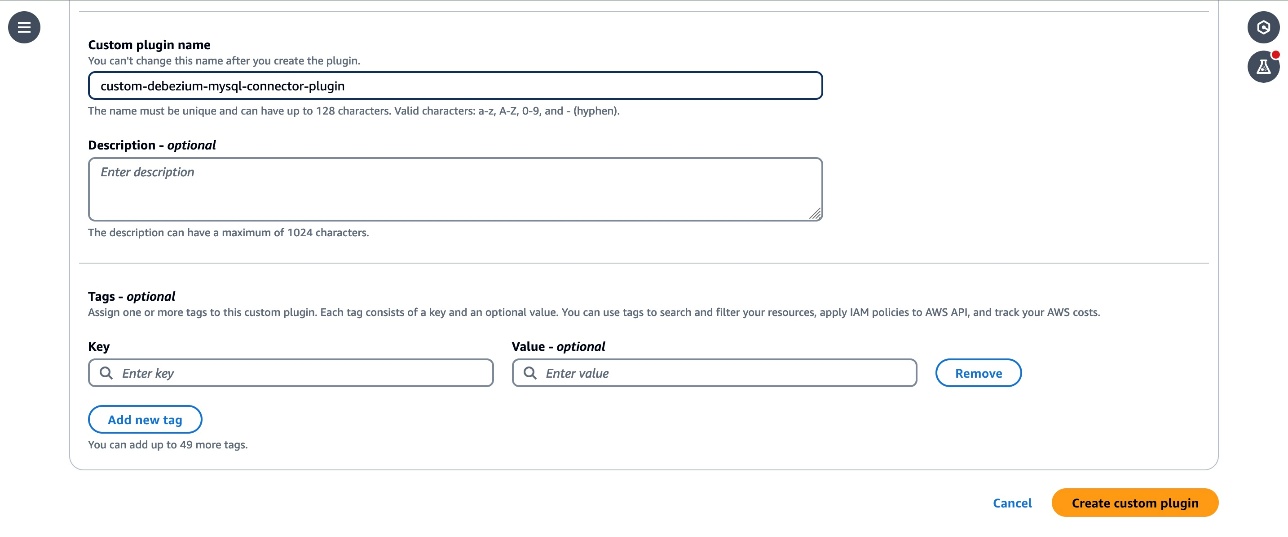
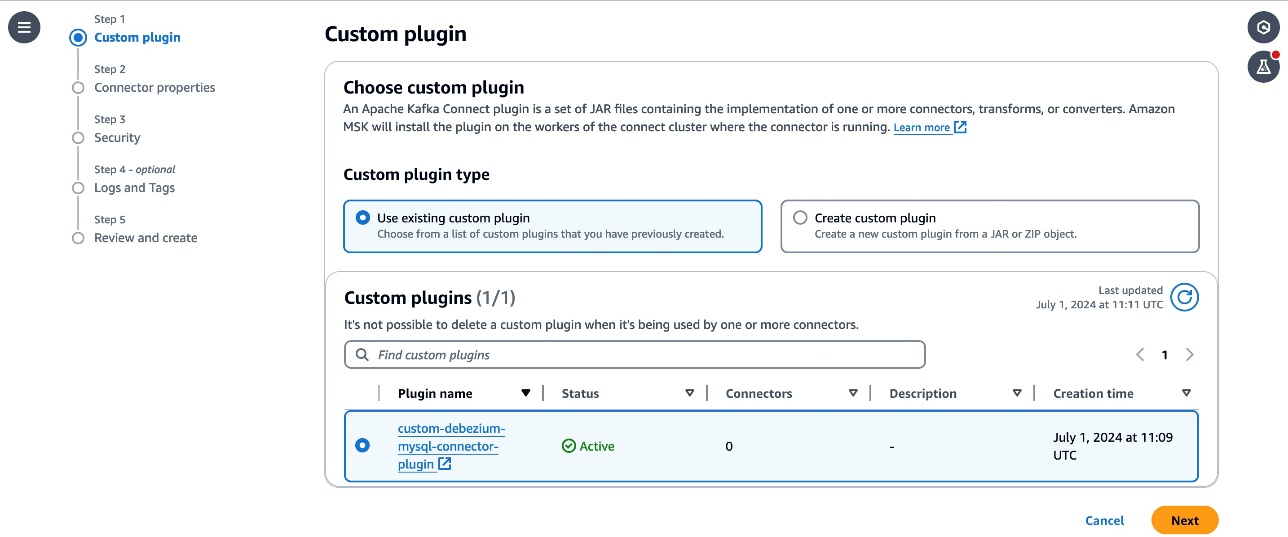
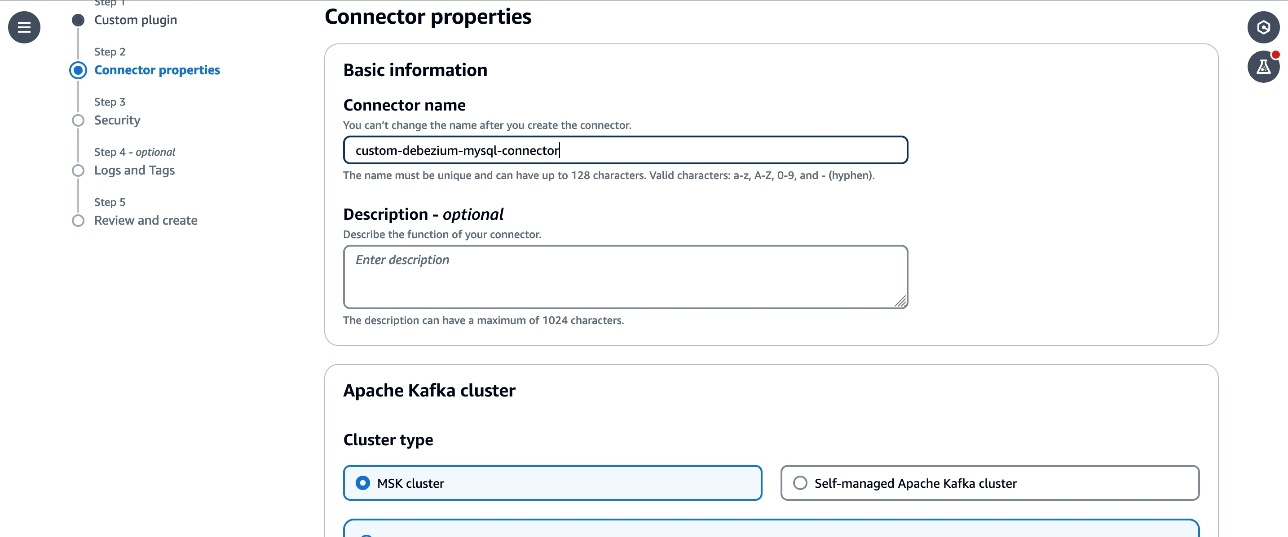
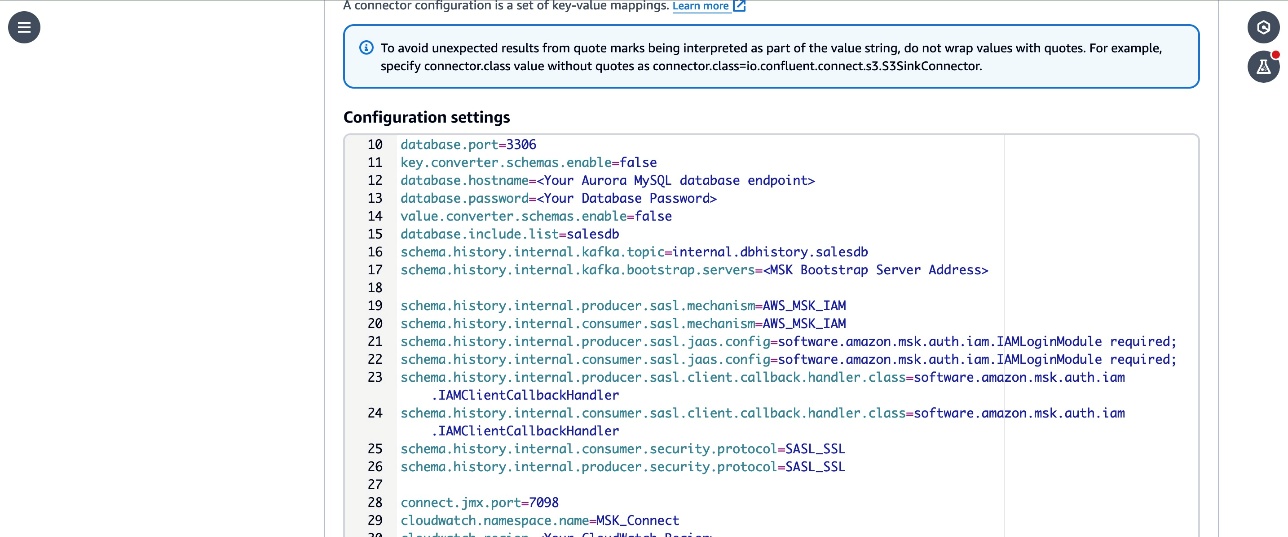
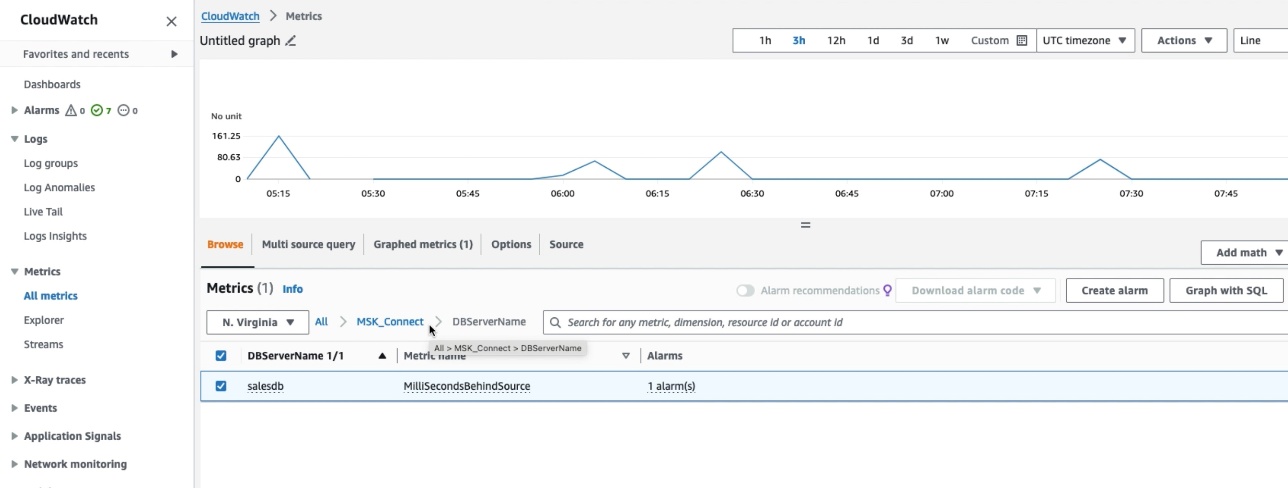
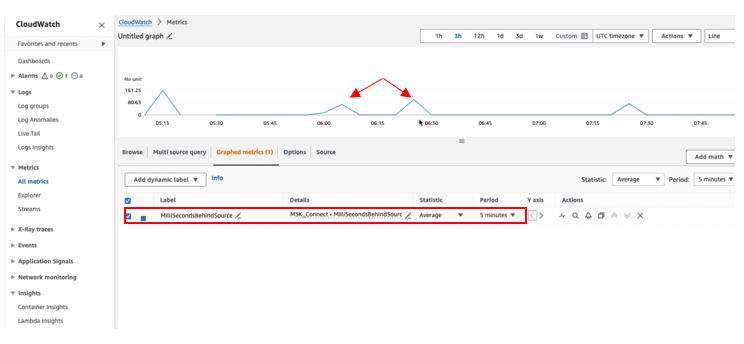
 Jaydev Nath is a Solutions Architect at AWS, where he works with ISV customers to build secure, scalable, reliable, and cost-efficient cloud solutions. He brings strong expertise in building SaaS architecture on AWS with a focus on Generative AI and data analytics technologies to help deliver practical, valuable business outcomes for customers.
 David John Chakram is a Principal Solutions Architect at AWS. He specializes in building data platforms and architecting seamless data ecosystems. With a profound passion for databases, data analytics, and machine learning, he excels at transforming complex data challenges into innovative solutions and driving businesses forward with data-driven insights.
 Sharmila Shanmugam is a Solutions Architect at Amazon Web Services. She is passionate about solving the customers’ business challenges with technology and automation and reduce the operational overhead. In her current role, she helps customers across industries in their digital transformation journey and build secure, scalable, performant and optimized workloads on AWS.


 Tarun Rai Madan is a Principal Product Manager at Amazon Web Services (AWS). He specializes in serverless technologies and leads product strategy to help customers achieve accelerated business outcomes with event-driven applications, using services like AWS Lambda, AWS Step Functions, Apache Kafka, and Amazon SQS/SNS. Prior to AWS, he was an engineering leader in the semiconductor industry, and led development of high-performance processors for wireless, automotive, and data center applications.
 Masudur Rahaman Sayem is a Streaming Data Architect at AWS with over 25 years of experience in the IT industry. He collaborates with AWS customers worldwide to architect and implement sophisticated data streaming solutions that address complex business challenges. As an expert in distributed computing, Sayem specializes in designing large-scale distributed systems architecture for maximum performance and scalability. He has a keen interest and passion for distributed architecture, which he applies to designing enterprise-grade solutions at internet scale.


 Masudur Rahaman Sayem is a Streaming Data Architect at AWS with over 25 years of experience in the IT industry. He collaborates with AWS customers worldwide to architect and implement sophisticated data streaming solutions that address complex business challenges. As an expert in distributed computing, Sayem specializes in designing large-scale distributed systems architecture for maximum performance and scalability. He has a keen interest and passion for distributed architecture, which he applies to designing enterprise-grade solutions at internet scale.


 Umesh Chaudhari is a Streaming Solutions Architect at AWS. He works with AWS customers to design and build real time data processing systems. He has 13 years of working experience in software engineering including architecting, designing, and developing data analytics systems.
 Vishal Khatri is a Sr. Technical Account Manager and Analytics specialist at AWS. Vishal works with State and Local Government helping educate and share best practices with customers by leading and owning the development and delivery of technical content while designing end-to-end customer solutions.