Tag Archives: Expert (400)

Build adaptive AI interfaces with the AG-UI protocol, agent swarms, and Nova Act on AWS

Post Syndicated from Anand Bilgaiyan original https://aws.amazon.com/blogs/architecture/build-adaptive-ai-interfaces-with-the-ag-ui-protocol-agent-swarms-and-nova-act-on-aws/

Your generative AI applications produce different results each time they run. One medical scan shows a single fracture, and another reveals twenty ambiguous regions that require expert review. Static interfaces can’t adapt to this variability.

In this post, we show you how to build interfaces that automatically adapt to your AI’s variable outputs. This approach reduces interface development time and removes the need for custom integration code by using the AG-UI protocol, the Strands Agents Software Development Kit (SDK), and Amazon Nova Act. You learn to build adaptive interfaces using the agent-to-UI (AG-UI) protocol for dynamic UI generation, the Strands Agents SDK Swarm pattern for multi-agent collaboration, and Amazon Nova Act for legacy system integration. After reading this post, you understand when to use adaptive interfaces and how to deploy them in your applications.

The problem with static interfaces

You design screens with fixed layouts, predetermined controls, and static data binding. This works well when your application’s output space is known and consistent. An ecommerce checkout page needs the same fields for every transaction. A dashboard displays the same metrics regardless of the data. Static interfaces excel at these predictable scenarios.

AI-driven applications introduce new requirements. Consider two scenarios when you review bone X-rays. In the first scenario, one image shows a single obvious fracture requiring minimal interface controls. In the second scenario, another image reveals three subtle regions where multiple AI agents must debate findings, track confidence progression, and reach consensus before presenting results. A static interface optimized for the first scenario lacks the controls needed for the second. An interface built for the second scenario presents unnecessary complexity in the first scenario with empty panels and unused controls.

This problem appears in multiple domains. Fraud detection systems encounter variable evidence chains. Legal document review surfaces unpredictable numbers of relevant clauses. Security event response reveals different threat patterns requiring different analysis tools. Domains where AI discovers things dynamically rather than classifying into predetermined categories face this architectural challenge.

The core challenge is that AI agents discover and reason about the world dynamically, while traditional interface design assumes static, predetermined outputs.

Business impact

This mismatch costs development teams significant time and creates poor user experiences. You spend weeks building interface variations to handle different scenarios, then maintain multiple code paths as your AI models evolve. Your users face either overwhelming complexity when AI finds simple results, or insufficient controls when AI discovers complex patterns requiring deeper analysis. The development cost compounds as you add new AI capabilities. Each new agent or model requires rethinking your entire interface architecture.

Solution overview

Three AWS technologies address this challenge, so you can build interfaces that adapt to what AI agents discover.

The AG-UI protocol offers standardized streaming for agent-to-user interface (UI) communication. Before AG-UI, connecting agents to interfaces required custom code for each framework. You built custom WebSocket formats, polling mechanisms, and bespoke integration code every time you switched agent frameworks or added new capabilities. AG-UI removes this work by providing a standard format of typed events that stream over Server-Sent Events (SSE). Agent frameworks emit AG-UI events, and frontends consume them, creating a universal contract so you can swap frameworks without rewriting integration code.

The Strands Agents SDK offers the Swarm pattern for peer-to-peer multi-agent collaboration. In swarm patterns, your agents operate as peers that share hypotheses and iteratively refine findings until reaching consensus. This debate process, visible to you in real time, builds trust and catches errors that single-agent systems miss. For medical imaging, the swarm pattern mirrors how radiologists consult specialists, with multiple expert perspectives converging on accurate diagnoses.

Amazon Nova Act offers browser-based automation using natural language commands, so your AI agents can interact with legacy systems through their web interfaces. Your agent navigates login screens, searches for related records, fills form fields, and captures confirmation numbers, while streaming actions back to the primary interface so you can observe the process.

These three technologies work together naturally: AG-UI adapts your interface to swarm findings, the swarm produces explainable multi-agent analysis, and Nova Act bridges the gap with legacy systems that lack API access.

Prerequisites

Before starting, verify you have:

Required AWS Resources:

  • AWS account with Amazon Bedrock access in a supported region (us-east-1, us-west-2, or eu-west-1)
  • Your Identity and Access Management (IAM) user or role needs these specific permissions:
    • bedrock:InvokeModel – For calling foundation models.
    • bedrock:CreateAgent and bedrock:CreateAgentActionGroup – For agent deployment.
    • lambda:CreateFunction and lambda:InvokeFunction – For serverless compute.
    • s3:PutObject and s3:GetObject – For file storage.
    • dynamodb:PutItem and dynamodb:GetItem – For state management.
    • secretsmanager:GetSecretValue – For credential retrieval.
    • logs:CreateLogGroup and logs:PutLogEvents – For Amazon CloudWatch logging.

Development Environment:

  • Python 3.9+ with pip installed.
  • Node.js 16+ and React 18+ installed.
  • AWS Command Line Interface (CLI) configured with your credentials.

Technical Skills:

  • Intermediate Python programming experience.
  • Familiarity with event-driven architectures (your interface listens for messages from agents and updates in real time, similar to how chat applications work).
  • Basic understanding of Representational State Transfer (REST) APIs and Server-Sent Events (SSE).

Data protection and HIPAA compliance

This solution processes Protected Health Information (PHI) including medical images, patient MRN, and clinical findings. Apply the following safeguards before deploying to any environment handling real patient data.

Encryption at rest — Configure SSE-KMS with a customer managed key on all Amazon S3 buckets storing medical images. Enable encryption with a customer managed AWS KMS key on all DynamoDB tables storing session state, conversation history, and analysis findings.

Encryption in transit — Enforce TLS 1.2+ on all connections. Attach a bucket policy denying all S3 actions when aws:SecureTransport is false. Do not override DynamoDB SDK endpoints to HTTP. Do not set ignore_https_errors=True on Nova Act workflows. If the legacy system uses self-signed certificates, add its CA to your runtime trust store.

S3 Block Public Access — Enable Block Public Access at the account level and on every bucket in this solution. Medical images must never be exposed through public bucket policies or ACLs.

HIPAA-eligible services and BAA — All AWS services in this architecture (Amazon Bedrock, Amazon S3, DynamoDB, Lambda, API Gateway, CloudFront, Cognito, Secrets Manager, CloudWatch) are HIPAA-eligible. Before processing PHI, execute a Business Associate Agreement (BAA) with AWS covering these services.

PHI minimization — Never write MRN, patient name, or clinical findings to plaintext logs. Enable CloudWatch Logs data protection policies to detect and mask PHI patterns automatically. Suppress Nova Act trajectory logging during steps that display patient data. Verify Cognito JWT on the SSE endpoint before emitting any PHI-bearing event.

Important: Code samples in this post are for educational purposes. Review all configurations against your organization’s HIPAA Security Rule implementation before production deployment.

Architecture

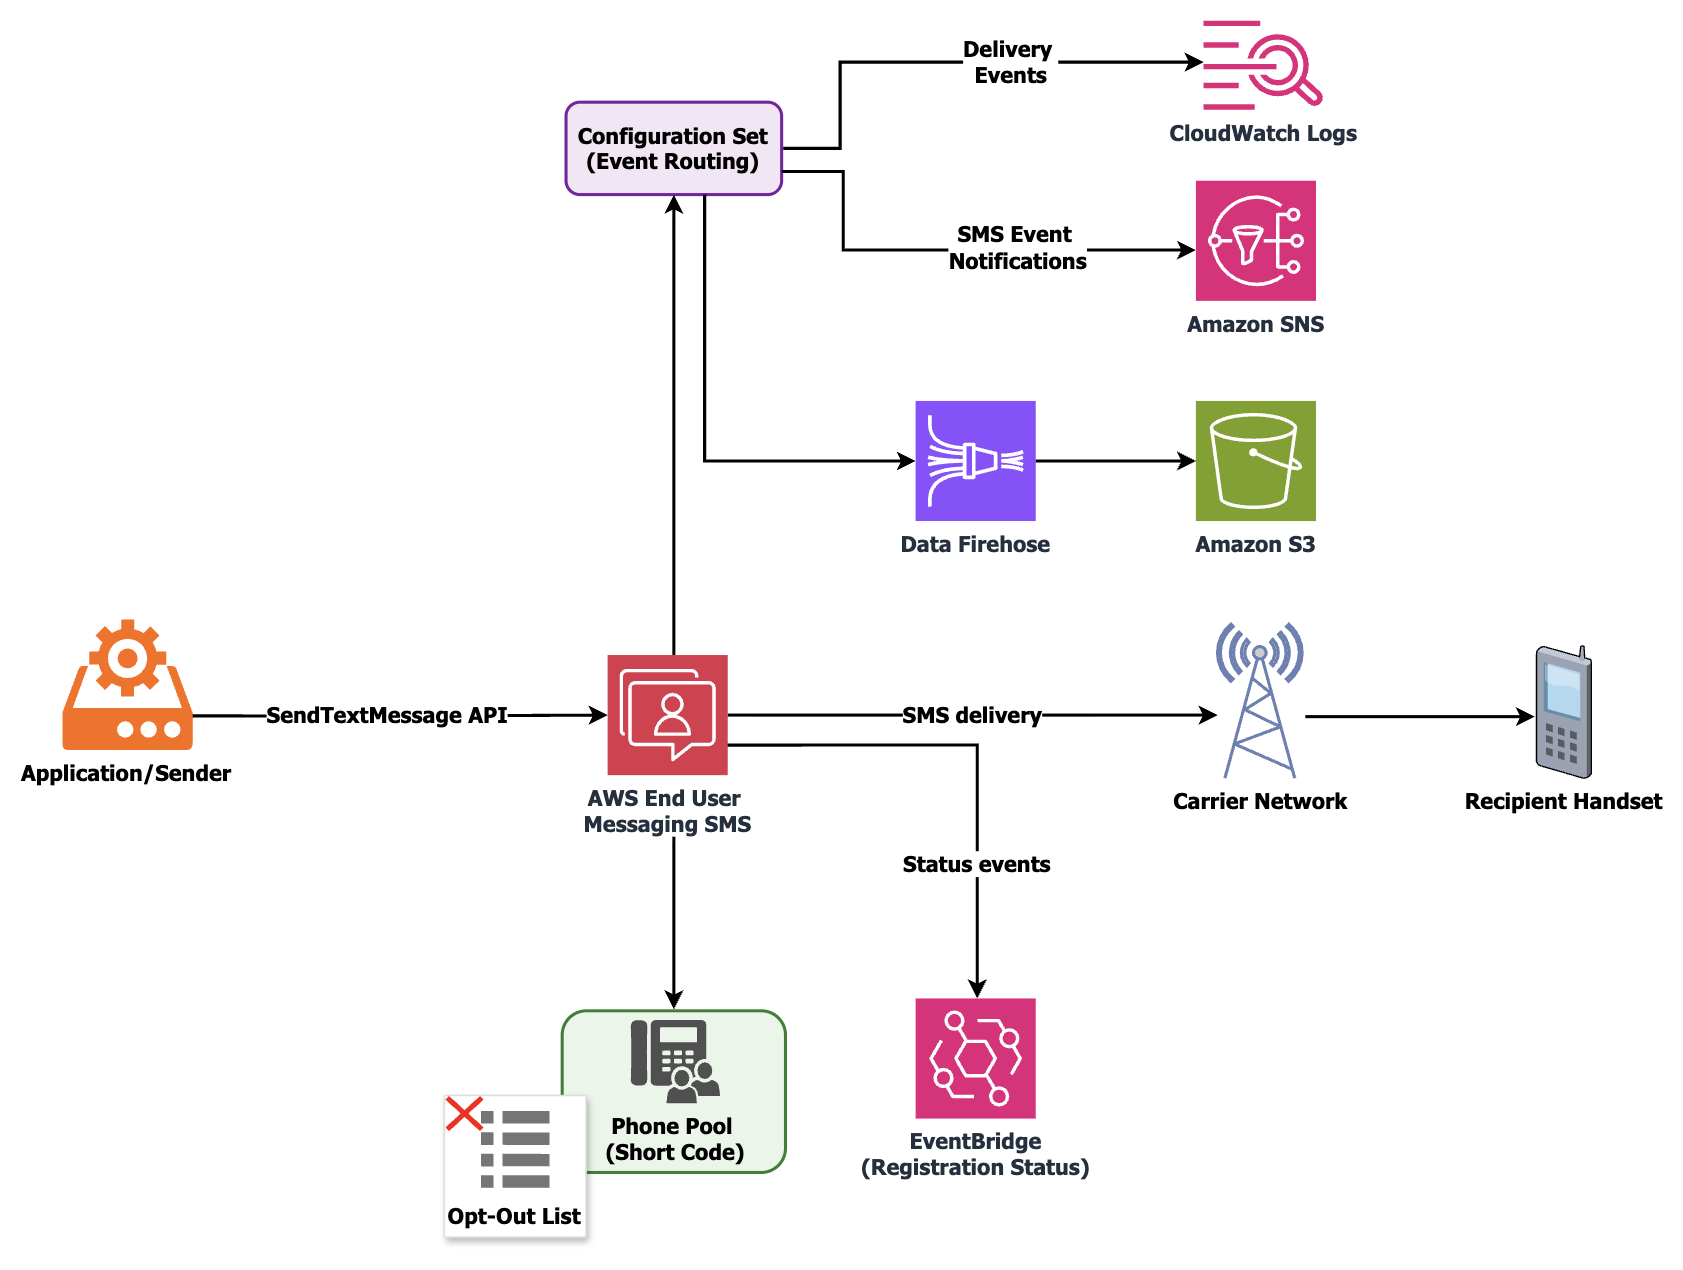
You implement an orchestrator pattern where your frontend interacts with a single entry point that internally coordinates specialized sub-agents. The solution follows this pattern: your React app sends requests to Amazon API Gateway, which triggers AWS Lambda functions that coordinate AI agents through Amazon Bedrock, then streams results back over Server-Sent Events. We use Amazon Bedrock AgentCore, a platform to build, connect, and optimize agents at scale with any framework or model.
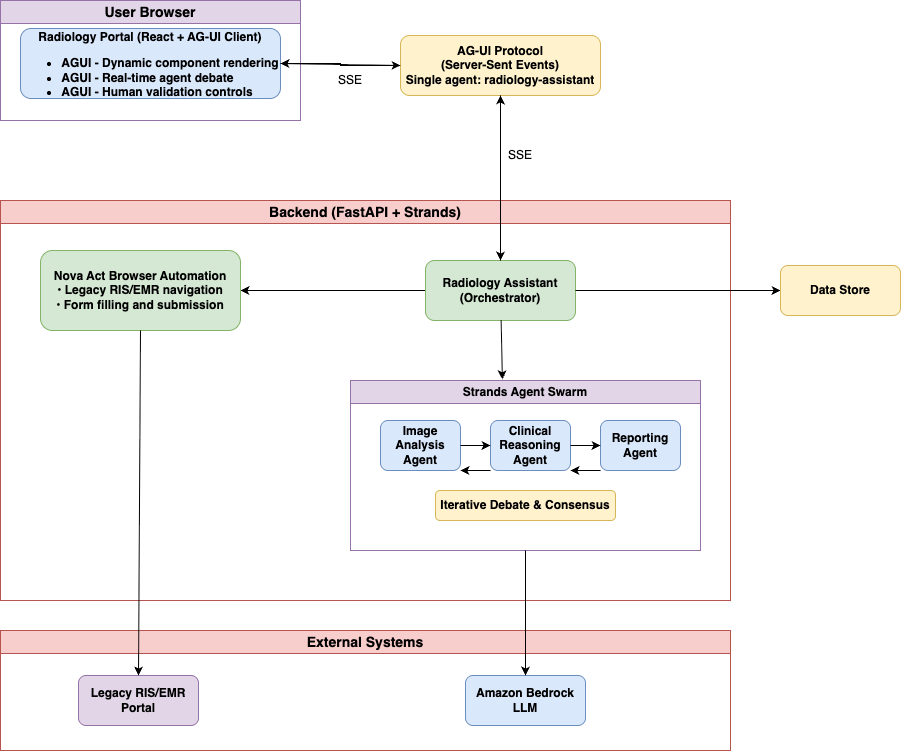
Logical view of the radiology portal: the React AG-UI client streams over SSE to a backend orchestrator that coordinates a Strands agent swarm, Nova Act browser automation, a data store, the legacy RIS/EMR portal, and Amazon Bedrock

Figure 1: Logical view of the adaptive interface, showing the AG-UI client, the backend orchestrator, the Strands agent swarm, and integrations with legacy systems and Amazon Bedrock
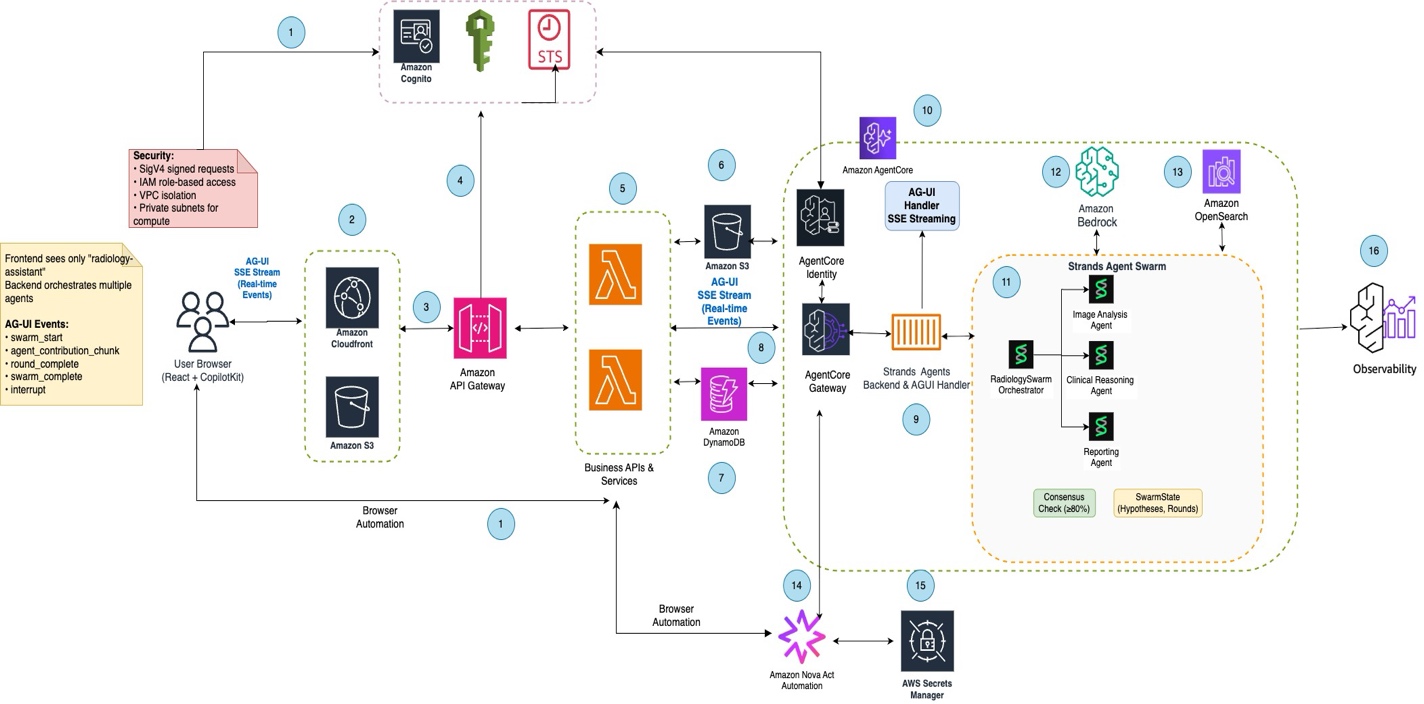
Detailed AWS architecture with 16 numbered components spanning Amazon Cognito and AWS STS, Amazon CloudFront and Amazon S3, Amazon API Gateway, AWS Lambda, Amazon DynamoDB, Amazon Bedrock AgentCore, the Strands agent swarm, Amazon Bedrock, Amazon OpenSearch Serverless, Amazon Nova Act, and AWS Secrets Manager

Figure 2: End-to-end AWS architecture showing the 16 components that deliver authentication, content delivery, agent orchestration, foundation model inference, and legacy system automation

Architecture components

The architecture consists of 16 integrated components working together:

① User authentication You authenticate through Amazon Cognito, which provides secure identity management and generates JWT tokens for accessing the radiology portal application.

② Content delivery Amazon CloudFront serves the React application and static assets from Amazon S3, providing global low-latency access and caching for optimal performance.

③ API Gateway Amazon API Gateway handles both REST API requests and Server-Sent Events (SSE) connections, providing the entry point for client-server communication.

④ Authorization of user API request with token validation

⑤ Backend processing AWS Lambda functions act as the AG-UI handler, managing authentication, invoking agents through Amazon Bedrock AgentCore Gateway, and formatting responses as SSE streams.

⑥ Image storage Amazon S3 stores medical images with SSE-KMS encryption using a customer managed key. S3 Block Public Access is enabled at the bucket level. Lambda generates short-lived, tightly scoped pre-signed URLs for secure direct uploads, pinned to the PUT method, scoped to a per-user key prefix, restricted to the application/dicom content type, and set to expire in 300 seconds. A bucket policy enforces maximum upload size through the s3:content-length-range condition and denies requests where aws:SecureTransport is false.

⑦ Session management Amazon DynamoDB maintains session state, conversation history, analysis findings, and agent registry data for stateful multi-turn interactions.

⑧ AgentCore Gateway Amazon Bedrock AgentCore Gateway serves as the orchestration layer, routing agent requests, managing sessions, coordinating multi-agent workflows, and load balancing across runtime instances.

⑨ AG-UI handler A specialized component within AgentCore that manages AG-UI protocol events, formatting agent responses as standardized events for dynamic UI rendering.

⑩ AgentCore runtime AgentCore Runtime provides the execution environment for agent instances, running the Strands Agent Swarm with isolated runtime instances for each agent type.

⑪ Agent swarm execution The Strands Agent Swarm consists of three specialized agents (Image Analysis, Clinical Reasoning, Reporting) that collaborate through iterative debate rounds to reach consensus.

⑫ Foundation model inference Amazon Bedrock provides access to the Claude Sonnet foundation model for reasoning, interpretation, and natural language generation across agents using a large language model (LLM).

⑬ Knowledge base retrieval Amazon OpenSearch Serverless stores medical knowledge base with vector embeddings, providing semantic search for relevant medical literature and clinical guidelines.

⑭ Legacy system automation Amazon Nova Act performs browser-based automation to submit validated findings to a legacy hospital’s Radiology Information System (RIS) and Electronic Medical Record (EMR) systems, with each action streamed back to your UI.

⑮ Credential management AWS Secrets Manager securely stores and rotates credentials for legacy system access, providing Nova Act with authentication details at runtime.

⑯ Observability and monitoring Amazon CloudWatch captures logs and metrics, with data protection policies enabled to detect and mask PHI. AWS Distro for OpenTelemetry (ADOT) provides distributed tracing with AWS X-Ray-compatible trace export. AWS Security Token Service (AWS STS) manages temporary security credentials.

Key architectural decisions

Your frontend sees one agent (radiology-assistant), not three, through the orchestrator pattern. This simplifies integration and encapsulates workflow complexity. The orchestrator internally coordinates the swarm based on analysis stage.

Rather than generating arbitrary HTML, agents select from themed, accessible components (ROICard, DebatePanel, ConfidenceMeter). This balances flexibility with design consistency and security through the predefined component library approach.

SSE provides real-time updates as agents work through the streaming protocol. You see agent contributions character by character, creating transparency into the reasoning process.

Your frontend exposes state (current findings, validation decisions) to agents through bidirectional state synchronization. Agents update state through actions. This synchronization supports human-in-the-loop workflows where agents pause for validation before proceeding.

Solution walkthrough

The following steps walk through the solution, from authentication and swarm configuration to the AG-UI endpoint, legacy system integration, and deployment.

Step 0: Configure authentication

Add JWT validation to your API endpoint to enforce authentication before processing requests containing PHI.

from fastapi import Depends, HTTPException, Request
import os

COGNITO_USER_POOL_ID = os.environ["COGNITO_USER_POOL_ID"]
COGNITO_APP_CLIENT_ID = os.environ["COGNITO_APP_CLIENT_ID"]

async def verify_token(request: Request):
    """Validate Cognito JWT from Authorization header."""
    token = request.headers.get("Authorization", "").replace("Bearer ", "")
    if not token:
        raise HTTPException(status_code=401, detail="Missing authorization")
    # Validate token against Cognito JWKS endpoint
    # See: https://docs.aws.amazon.com/cognito/latest/developerguide/amazon-cognito-user-pools-using-tokens-verifying-a-jwt.html
    return validate_jwt(token, COGNITO_USER_POOL_ID, COGNITO_APP_CLIENT_ID)

@app.post("/api/agui")
async def agui_endpoint(request: Request, user=Depends(verify_token)):
    ...

Full Amazon Cognito user pool setup (pool creation, hosted UI, and token exchange) is covered in the Amazon Cognito Developer Guide. This post focuses on the agent architecture layer.

Step 1: Install the Strands Agents SDK

Install required packages by running the following command:

pip install strands-agents ag-ui-strands fastapi uvicorn

This command installs the required packages for building your multi-agent swarm, including the Strands framework, AG-UI integration, and web server components.

Step 2: Configure your swarm agents

Create specialized agents for your swarm by adding the following code to your project:

from strands import Agent
from strands.models import BedrockModel
from typing import Dict, List, AsyncGenerator
import os

region = os.environ.get("AWS_REGION", "us-east-1")

class RadiologySwarm:
    """Coordinates multi-agent analysis with visible debate."""

    def __init__(
        self,
        consensus_threshold: float = 0.80,
        max_rounds: int = 5,
    ):
        self.consensus_threshold = consensus_threshold
        self.max_rounds = max_rounds
        self.agents = self._initialize_agents()
        self.hypotheses = []

    def _initialize_agents(self) -> List[Agent]:
        """Create specialized agents for swarm."""
        model = BedrockModel(
            model_id=os.environ.get("BEDROCK_MODEL_ID", "us.anthropic.claude-sonnet-4-20250514-v1:0")
        )
        return [
            Agent(
                name="image_analysis",
                system_prompt="Detect abnormal patterns in medical images...",
                model=model,
            ),
            Agent(
                name="clinical_reasoning",
                system_prompt="Validate findings with clinical context...",
                model=model,
            ),
            Agent(
                name="reporting",
                system_prompt="Structure findings in clinical format...",
                model=model,
            ),
        ]

    async def analyze_with_debate_stream(
        self,
        image_data: bytes,
        patient_context: Dict,
    ) -> AsyncGenerator[Dict, None]:
        """Stream swarm analysis events for real-time UI updates."""
        # Implementation continues in next steps...
        pass

Note: The agents use a foundation model accessed through Amazon Bedrock. The example defaults to Claude Sonnet 4, but you should select a currently active model from the Amazon Bedrock model lifecycle page for your AWS Region. Read the model ID from an environment variable so you can update it without code changes as newer models become available. Amazon Bedrock retires models on a published lifecycle schedule, so hardcoding a model ID risks failure when that model reaches end of life. Check the Amazon Bedrock model lifecycle page and supported Regions, and use an environment variable or AWS Systems Manager Parameter Store to manage the model ID externally.

This code creates three specialized agents (Image Analysis, Clinical Reasoning, Reporting) that work together as peers in a swarm pattern, sharing hypotheses and refining findings through iterative debate until reaching consensus.

Step 3: Implement consensus mechanism

Configure your swarm to continue debate rounds until agents reach consensus or exhaust maximum iterations:

from typing import Dict, List

class RadiologySwarm:
    """Consensus mechanism implementation."""

    def __init__(
        self,
        consensus_threshold: float = 0.80,
        max_rounds: int = 5,
    ):
        self.consensus_threshold = consensus_threshold
        self.max_rounds = max_rounds
        self.hypotheses = []

    async def analyze_with_debate_stream(
        self,
        image_data: bytes,
        patient_context: Dict,
    ):
        """Stream swarm analysis with consensus checking."""
        yield {"type": "swarm_start", "max_rounds": self.max_rounds}
        for round_num in range(1, self.max_rounds + 1):
            # Each agent contributes based on current hypotheses
            for agent in self.agents:
                try:
                    context = {
                        "image_data": image_data,
                        "patient_context": patient_context,
                        "round": round_num,
                    }
                    async for chunk in agent.stream_response(context):
                        yield {
                            "type": "agent_contribution_chunk",
                            "agent": agent.name,
                            "round": round_num,
                            "text": chunk,
                        }
                except Exception as e:
                    yield {
                        "type": "agent_error",
                        "agent": agent.name,
                        "round": round_num,
                        "error": str(e),
                    }
            # Check if consensus reached after all agents contribute
            if self._check_consensus():
                yield {"type": "consensus_reached", "round": round_num}
                break
        yield {"type": "swarm_complete", "findings": self.hypotheses}

    def _check_consensus(self) -> bool:
        """Verify hypotheses meet confidence threshold."""
        if not self.hypotheses:
            return False
        # Check if all hypotheses have confidence above threshold
        for hypothesis in self.hypotheses:
            if hypothesis.get("confidence", 0) < self.consensus_threshold:
                return False
        return True

Your swarm reaches consensus when proposed findings achieve confidence scores above your configured threshold (80% for this example). Confidence progresses as agents validate or debate each other.

In the first example of subtle fracture detection, Round 1 shows the Image Agent proposing a Region of Interest (ROI) with confidence above 80%. Round 2 shows the Clinical Agent validating with anatomical context, maintaining confidence above the threshold. Round 3 shows agents agreeing on clinical significance, reaching consensus when the three agents reach confidence scores above the configured threshold.

In the second example of false positive challenge, Round 1 shows the Image Agent proposing an ROI with confidence above the threshold. Round 2 shows the Clinical Agent challenging it as an artifact, with confidence dropping below 80%. Round 3 shows the Image Agent acknowledging the challenge, with confidence dropping further. Round 4 shows agents continuing debate without consensus. Round 5 shows maximum rounds reached, with the finding marked as disputed.

This iterative refinement, visible to you in real time, provides explainability that black-box AI systems can’t match.

Step 4: Set up the AG-UI protocol endpoint

Create a streaming endpoint by adding the following code:

from fastapi import FastAPI, Request
from fastapi.responses import StreamingResponse
import json

app = FastAPI()

@app.post("/api/agui")
async def agui_endpoint(request: Request):
    """AG-UI streaming endpoint emitting typed events."""
    body = await request.json()

    async def event_stream():
        """Stream standardized AG-UI events."""
        swarm = RadiologySwarm()
        async for event in swarm.analyze_with_debate_stream(
            image_data=body["image_data"],
            patient_context=body["patient_context"],
        ):
            yield format_sse_event(event)

    return StreamingResponse(
        event_stream(),
        media_type="text/event-stream",
    )

def format_sse_event(event: Dict) -> str:
    """Format as Server-Sent Event."""
    return f"data: {json.dumps(event)}\n\n"

This code creates a streaming endpoint that emits standardized AG-UI events, so your frontend receives real-time updates as agents work without requiring custom integration code for each agent framework.

The AG-UI protocol defines event types that cover agent-to-UI communication needs. Instead of custom formats, agents emit structured events over SSE, and frontends subscribe to this stream and react to each event type. TEXT_MESSAGE_CONTENT streams agent reasoning or responses token by token for real-time visibility into agent thinking. STATE_DELTA provides incremental state updates for bidirectional synchronization between agent and interface. TOOL_CALL_START and TOOL_CALL_END show tool execution when agents invoke external functions or APIs. With UI_COMPONENT_SPEC, agents control which UI components appear and how they’re configured through interface element specifications.

Configure your frontend to subscribe to this stream and handle each event type:

// Frontend event handler
eventSource.onmessage = (event) => {
  const data = JSON.parse(event.data);
  switch (data.type) {
    case "text_message_content":
      appendAgentText(data.agent, data.text);
      break;
    case "state_delta":
      updateApplicationState(data.path, data.value);
      break;
    case "ui_component_spec":
      renderComponent(data.component, data.props);
      break;
  }
};

Step 5: Implement real-time agent debate visualization

Create interface components that make multi-agent collaboration visible to you by implementing the following visualization features:

A key benefit of the swarm pattern combined with AG-UI is making multi-agent collaboration visible. Rather than presenting you with final results from a black-box system, the interface shows agents debating findings in real time.

Your interface includes specialized components for visualizing agent collaboration. The agent contribution display shows each agent’s reasoning streaming character by character with a typing effect, indicating which agent is currently “thinking.” Color-coding distinguishes agents (blue for Image Analysis, purple for Clinical Reasoning, cyan for Reporting). The confidence timeline uses a line graph to show how confidence evolves across rounds. Increasing confidence (72% → 78% → 85%) indicates agents converging on consensus. Decreasing confidence (68% → 52% → 45%) shows successful challenge of a false positive. Evidence cards display each region of interest with a status badge (Challenged, Consensus, Disputed) based on the debate outcome, an AI-generated summary of key reasoning points, and an expandable section showing complete agent contributions for radiologists who want detailed analysis.

This visibility serves multiple purposes. For explainability, you see why agents reached conclusions, not only what they concluded. For error detection, visible debate helps you spot flawed reasoning. For confidence calibration, watching agents debate each other helps you assess reliability. For educational value, radiologists learn from agent reasoning, improving their own analysis.

Step 6: Integrate Amazon Nova Act for legacy systems

Implement browser automation to submit findings to legacy systems by adding the following code:

import json
import boto3
from typing import Dict

class LegacyRISSubmission:
    """Browser automation for legacy RIS submission."""

    def __init__(
        self, secret_name: str = "ris-credentials", region_name: str = "us-east-1"
    ):
        """Initialize with AWS Secrets Manager configuration."""
        self.secret_name = secret_name
        self.secretsmanager = boto3.client("secretsmanager", region_name=region_name)

    def _get_credentials(self) -> Dict:
        """Retrieve credentials from AWS Secrets Manager."""
        response = self.secretsmanager.get_secret_value(SecretId=self.secret_name)
        return json.loads(response["SecretString"])

    def submit_report(self, report_data: Dict, ris_url: str) -> Dict:
        """Submit validated findings to legacy RIS."""
        from nova_act import NovaAct
        from nova_act.types.workflow import Workflow
        creds = self._get_credentials()
        with Workflow(
            model_id="us.amazon.nova-act-v1:0",
            workflow_definition_name="radiology-submission"
        ) as workflow:
            with NovaAct(
                starting_page=f"{ris_url}/login",
                headless=True,
                workflow=workflow,
            ) as nova:
                # Authentication
                nova.act("Click on the username input field")
                nova.type_text(creds["username"], sensitive=True)
                nova.act("Click on the password input field")
                nova.type_text(creds["password"], sensitive=True)
                nova.act("Click Sign In button")
                # Patient lookup
                mrn = report_data["patient_mrn"]
                nova.act(f"Search for patient MRN '{mrn}'")
                nova.act("Click View Record button")
                # Report submission
                nova.act("Click New Report button")
                findings_text = report_data["findings_summary"]
                nova.act(f"Fill findings textarea with: {findings_text}")
                nova.act("Upload annotated image file")
                nova.act("Click Submit Report button")
                # Capture confirmation
                result = nova.act("Find and return the RPT- confirmation number")
        return {"status": "success", "confirmation": result, "mrn": mrn}

Security note: Nova Act captures prompts and screenshots as trajectory data. Never interpolate credentials or PHI into act() commands. Use type_text with sensitive=True to prevent credential capture in logs and trajectories. In production, suppress trajectory capture entirely for authentication steps, or route trajectory storage to a KMS-encrypted, access-controlled bucket subject to your BAA

Many enterprise systems, particularly in healthcare, lack modern APIs. Hospital RIS and EMR systems often run on decades-old technology stacks that can’t be modified without significant effort. Amazon Nova Act offers a pragmatic solution: browser-based automation using natural language commands.

This code implements browser automation that interacts with legacy systems through their existing web interfaces, retrieving credentials securely from AWS Secrets Manager and streaming each action back to your interface for transparency.

Each Nova Act command streams back to the radiology portal, so you can observe the submission process. Your interface displays a live action log showing authentication, navigation, form filling, and confirmation capture. This transparency helps you understand what the automation is doing and intervene if issues arise.

Browser automation requires careful credential management. The implementation stores credentials in AWS Secrets Manager, retrieves them at runtime, and never exposes them to the frontend. Audit logging captures Nova Act actions for compliance and troubleshooting. For production deployment, additional controls include IP allowlisting, session timeout enforcement, and multi-factor authentication where supported by legacy systems.

Step 7: Deploy to AWS

Configure DynamoDB tables with customer-managed KMS encryption:

import boto3

dynamodb = boto3.client("dynamodb")

dynamodb.create_table(
    TableName="radiology-sessions",
    KeySchema=[{"AttributeName": "session_id", "KeyType": "HASH"}],
    AttributeDefinitions=[{"AttributeName": "session_id", "AttributeType": "S"}],
    BillingMode="PAY_PER_REQUEST",
    SSESpecification={
        "Enabled": True,
        "SSEType": "KMS",
        "KMSMasterKeyId": "arn:aws:kms:us-east-1:ACCOUNT:key/YOUR-KEY-ID"
    },
)

Deploy your solution using Amazon Bedrock AgentCore, which offers managed runtime for agents with built-in identity, memory, and observability. AgentCore supports long-running tasks (up to 8 hours), asynchronous tool execution, and native CloudWatch integration, making it ideal for production deployments requiring minimal operational overhead.

Pattern selection guidance

Choosing the right architecture pattern depends on problem characteristics and requirements.

When to use dynamic agent-generated UIs

Characteristic Dynamic UI (AG-UI) Static UI (Traditional)
Output Variability High – unpredictable number/structure of results Low – consistent data structure
Multi-Agent Value Visible collaboration builds trust Single agent or no collaboration to show
Interface Complexity Varies per case Consistent across cases
Explainability Needs Important – users must understand reasoning Less important – results speak for themselves
Development Effort Higher – protocol integration, component library Lower – standard REST API

Swarm compared to other multi-agent patterns

Use swarm when multiple perspectives improve accuracy (peer review, consensus building), debate process offers value (explainability, error detection), no clear hierarchy exists (agents are peers, not supervisor/worker), and iterative refinement is beneficial (findings improve through rounds).

Use agents as tools when clear task decomposition exists (supervisor delegates to specialists), subtasks are independent (parallel execution possible), hierarchy is natural (manager coordinating experts), and no need for peer debate exists (each agent’s output stands alone).

Use sequential workflow when strict ordering is required (step B needs step A’s output), checkpoints are needed (validate before proceeding), process is well-defined (known stages, dependencies), and no benefit from parallel exploration exists (linear pipeline).

Use cases beyond medical imaging

This architectural pattern applies to domains with high output variability and multi-agent value. For fraud detection, you encounter variable evidence chains (1-20 suspicious transactions), multiple analyst perspectives (financial, behavioral, network analysis), and legacy banking systems requiring browser automation. For legal document review, you face unpredictable numbers of relevant clauses, expert opinions from different legal domains (contract law, regulatory compliance, risk assessment), and integration with legacy case management systems. For security event response, you deal with variable threat indicators, team collaboration (network analysis, malware analysis, threat intelligence), and legacy Security Information and Event Management (SIEM) systems without modern APIs.

Anti-patterns

Avoid this approach when you have simple classification (predetermined categories with fixed confidence scores), deterministic calculations (no uncertainty or debate needed), low-latency requirements (multi-round debate adds latency), cost-sensitive scenarios with predictable outputs (swarm pattern increases token usage), or minimal explainability needs (users trust results without seeing reasoning).

Clean up

To avoid incurring future charges, delete the resources you created while following this walkthrough. Delete them in the following order. The sequence removes the frontend and compute layers first, then the data stores, and finally the encryption keys and IAM roles, so no deletion fails because another resource still depends on it. Because this solution can process PHI, this teardown also removes any stored medical images, patient identifiers, and findings.

  1. Amazon CloudFront — Disable the distribution, let it propagate, then delete it. This stops traffic and releases the S3 app bucket.
  2. Amazon API Gateway — Delete the REST API and SSE endpoint.
  3. Amazon Bedrock AgentCore — Delete the Gateway, then the Runtime instances (and their identity, memory, and session resources). This stops all agent activity against the downstream services.
  4. AWS Lambda — Delete the AG-UI handler and any other functions.
  5. Amazon Bedrock model access — Confirm nothing is still invoking the models. Revoke access to Claude Sonnet or Amazon Nova Act if enabled only for this walkthrough.
  6. Amazon OpenSearch Serverless — Delete the knowledge base collection and its access, network, and encryption policies. OCUs bill hourly.
  7. Amazon DynamoDB — Delete the radiology-sessions table and any other tables you created.
  8. Amazon S3 — Empty (including all object versions) and delete the medical-image and app-hosting buckets.
  9. AWS Secrets Manager — Delete the legacy RIS/EMR credential secrets. A 7 to 30 day recovery window applies unless you force deletion.
  10. Amazon Cognito — Delete the user pool and app client.
  11. AWS KMS — Only now, schedule deletion of the customer managed keys used for Amazon S3 and DynamoDB. Deleting them earlier can make encrypted data unrecoverable.
  12. AWS IAM — Delete the roles and policies created for Lambda and AgentCore.
  13. Amazon CloudWatch — Delete the log groups, dashboards, and alarms (kept until last for troubleshooting).

Finally, review the AWS Billing and Cost Management console to confirm no unexpected charges remain.

Conclusion

In this post, we showed you how to build adaptive AI interfaces using three AWS technologies. You learned to use the AG-UI protocol for dynamic UI generation, apply Strands swarm patterns for multi-agent collaboration, and integrate Amazon Nova Act for legacy systems. Through a complete radiology assistant implementation, you saw how these technologies work together to handle variable AI outputs while maintaining explainability and practical enterprise integration.

The AG-UI protocol creates interfaces that adapt to what your agents discover, not what you anticipated. Use it when output variability is high and you can’t predetermine interface requirements. The Strands swarm pattern creates explainability through visible multi-agent debate. Use when multiple perspectives improve accuracy and you benefit from seeing reasoning processes. Amazon Nova Act bridges the gap with legacy systems lacking APIs. Use when browser automation is the only viable integration path and action transparency matters.

These technologies work together naturally because they address different aspects of the same problem: building AI systems that are flexible, explainable, and practical for real-world enterprise environments.

Next steps

Read related AWS blogs:

  • Multi-Agent Collaboration Patterns with Strands Agents and Amazon Nova.
  • Strands Agents SDK: A Technical Deep Dive into Agent Architectures and Observability.
  • Build a Drug Discovery Research Assistant using Strands Agents and Amazon Bedrock.


About the authors

Audit trails for autonomous agents with AWS DevOps Agent

Post Syndicated from Ben Peterson original https://aws.amazon.com/blogs/devops/audit-trails-for-autonomous-agents-with-aws-devops-agent/

Autonomous agents need audit trails. AWS DevOps Agent (DevOps Agent) investigates production incidents and proposes or applies fixes on your behalf. Every operation and security review then raises the same two questions: what did the agent do, and how do you understand its impact?

AWS DevOps Agent maintains an immutable, step-by-step record of its own reasoning and actions. This post shows how to capture the agent’s full operational trail using the agent journal, recommendations, Amazon EventBridge lifecycle events, and AWS CloudTrail. We then wire them into an audit pipeline built on Amazon EventBridge, AWS Lambda, and Amazon Simple Storage Service (Amazon S3).

By the end, you will have deployable audit patterns that show, for any investigation the agent runs, what it concluded, what it recommended, when it ran, and whether the fix landed.

Why auditing an autonomous agent is different

CloudTrail records the API calls made in your account, but an autonomous agent adds reasoning that CloudTrail doesn’t capture. “The agent ran a metric query” is far less valuable than “the agent concluded the Lambda was timing out because its security group blocks egress to the database.” The latter is a decision, and that’s what an agent audit needs to capture.

The four surfaces

AWS DevOps Agent exposes four surfaces. Two capture the agent’s output, what it found and what it advises, and two capture context: when it ran, and who configured the agent and its permissions.

The agent journal

The agent journal (API) is the heart of the audit trail. For every execution, AWS DevOps Agent records an ordered, immutable log of its reasoning step, sub-agent it dispatches, observations, findings, and root-cause summary. Journal entries cannot be modified once written, making them resistant to prompt injection and trustworthy as an audit record.

aws devops-agent list-journal-records \
  --agent-space-id <id> --execution-id <execution-id>

Each record carries a recordType: symptom, observation, finding, and investigation_summary / investigation_summary_md are what matters for audit. This is the surface you archive per investigation.

Recommendations polling

Recommendations (API) are cross-incident preventative advice. The agent generates these on a schedule through a goal, and each recommendation carries a status and a version. Each evaluation run writes new records rather than updating the previous run’s, so advice that persists week over week appears as a series of records. The superseded ones remain at whatever status they last held. “The agent recommended X, the same failure recurred Y weeks later, and here is every version of that advice in between” is something you reconstruct from the archived snapshots, because the API returns current and superseded records together. Recommendations have no Amazon EventBridge event. You capture them by polling on a schedule.

aws devops-agent list-recommendations --agent-space-id <id>

Amazon EventBridge lifecycle events

Amazon EventBridge is how you capture lifecycle transitions in real time. A successful investigation produces Created, In Progress, and Completed events. Each carries the execution_id you need to fetch the journal and a summary_record_id pointing at the root-cause summary. Investigations can also end as Failed, Timed Out, or Canceled, and mitigations emit their own parallel set.

AWS CloudTrail

CloudTrail records API calls made to the AWS DevOps Agent service and stamps agent-initiated service calls: invokedBy: aidevops.amazonaws.com. It doesn’t capture the agent’s investigation reads, the metric and log queries it runs while diagnosing an incident in your account’s trail. Use CloudTrail for control-plane accountability, and the journal for behavioral audit.

IAM: Action boundary

As with anything in AWS, the agent can only do what its AWS Identity and Access Management (IAM) role permits. During an investigation, AWS DevOps Agent assumes an Agent Space role. That role’s policies are the hard ceiling on its capabilities. You can inspect it directly:

aws iam list-attached-role-policies --role-name DevOpsAgentRole-AgentSpace-<suffix>

The AWS-managed AIOpsAssistantPolicy is attached to the default role. As of policy version 15, 848 of its actions are reads except 6 read-oriented query lifecycle operations. The only actions that change anything come from a companion policy: support:CreateCase and a service-linked-role creation scoped to the Amazon Resource Name (ARN) of a single role.

Keep that role least-privilege, and your audit surface stays small by construction. If you enable agent actions, a later section covers the write path which uses a separate actions role.

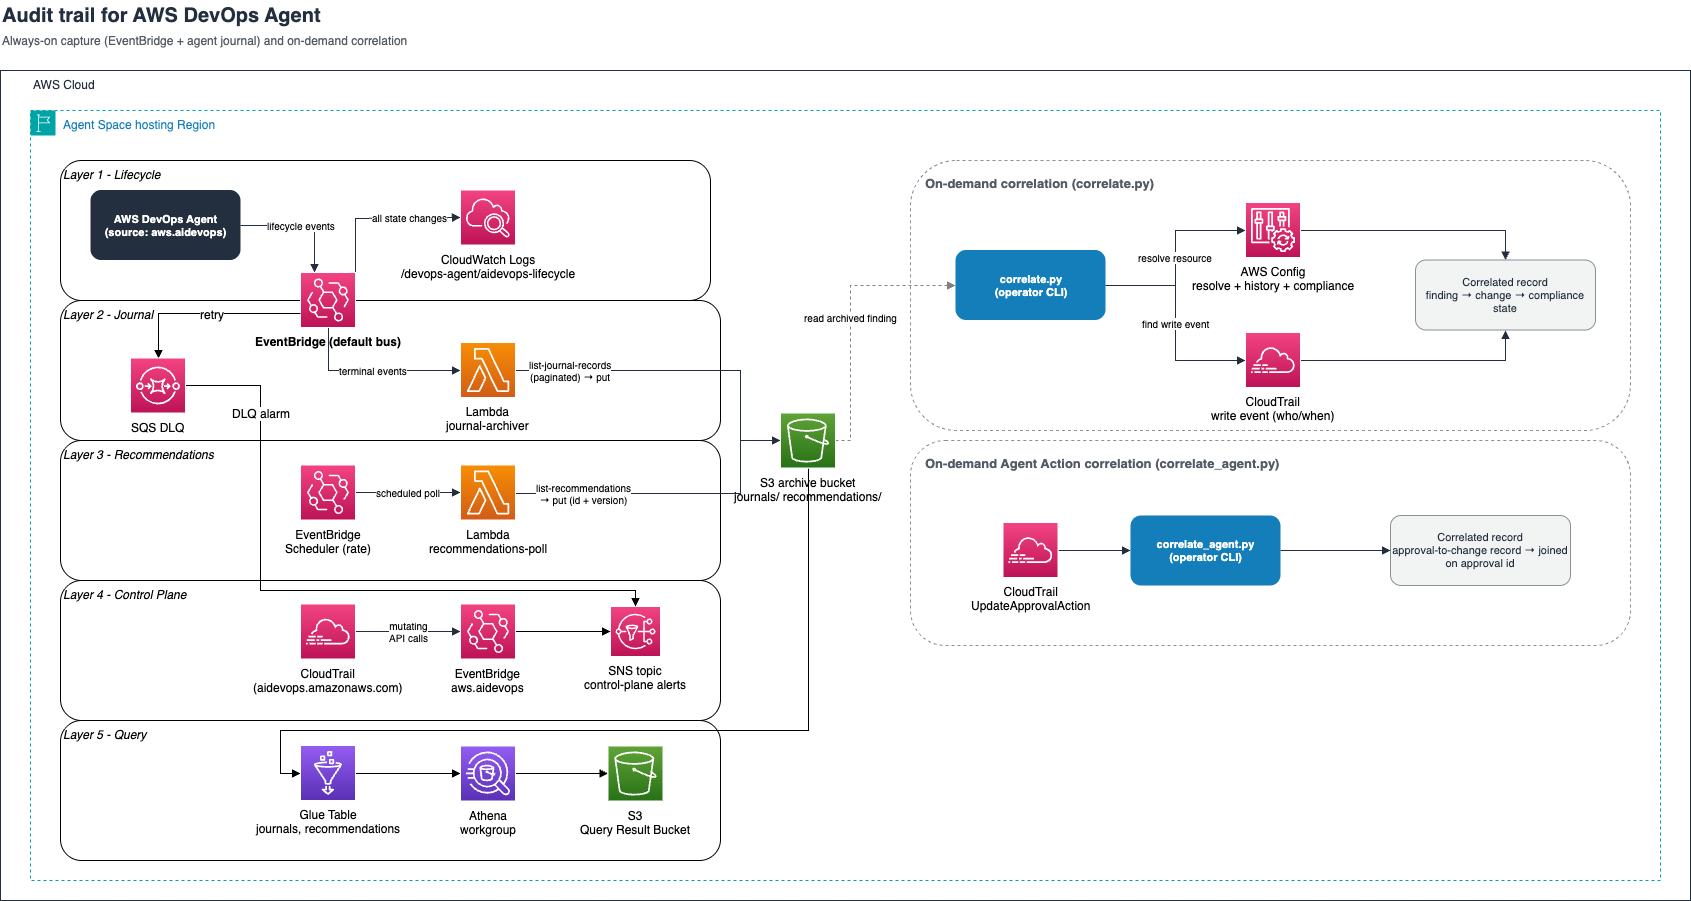
The reference architecture

The agent produces output that arrives two different ways, and this shapes how you capture each:

Agent output Delivery How you capture it Latency
Investigation lifecycle Push: Amazon EventBridge events React to events (rules + targets) Seconds
Recommendations Pull: no event emitted. Generated on goal cadence Poll list-recommendations on a schedule depends on your poll frequency

The journal itself has no dedicated event, but the terminal lifecycle event carries the execution_id you need to fetch it. The journal is push-triggered, pull-retrieved: the event tells you when to look, and the API gives you what to archive.

Five capture layers inside the Agent Space Region: lifecycle events to CloudWatch Logs, terminal events to a Lambda that archives journals to Amazon S3 with a dead-letter queue, a scheduled poll for recommendations, control-plane mutations to an SNS topic through Amazon EventBridge, and a Glue/Athena query layer. Two operator CLIs read the archive: correlate.py joins findings to AWS Config and CloudTrail, and correlate_agent.py joins agent actions to their approvals.

Figure 1: Reference architecture for auditing AWS DevOps Agent across five capture layers

Layer 1: Lifecycle capture. One Amazon EventBridge rule matching {"source":["aws.aidevops"]}, targeting an Amazon CloudWatch Logs (CloudWatch Logs) group directly. This durably records every lifecycle transition. Start here for operational visibility. If your primary goal is behavioral audit rather than operational visibility, deploy layer 2 alongside it.

Layer 2: Behavior capture. A second rule matches only terminal events and invokes a Lambda function. The function reads the execution_id from the event, calls list-journal-records, and writes the journal to Amazon S3. Subscribe to each terminal investigation and mitigation type. This is the layer that captures the agent’s decisions for the long term, including agent-based mitigations.

Layer 3: Recommendations snapshot. Because recommendations are generated on a schedule and have no event, capture them with an Amazon EventBridge Scheduler rule that invokes a Lambda function on a cadence (start daily). The function calls list-recommendations and writes each to Amazon S3, keyed on recommendation ID and version. It also calls list-goals in the same invocation, because a recommendation carries no field saying whether it is still current and the owning goal is the only thing that does. The journal captures what the agent found, and this layer captures what it advised and what you did about it.

Layer 4: Control-plane alerting. On your existing organization trail, alert on mutating aidevops.amazonaws.com events including UpdateApprovalAction, which is produced on elevated actions. This is your tripwire for changes to the agent itself.

Layer 5: Query. AWS Glue Data Catalog tables and an Amazon Athena (Athena) workgroup over the archived journals, recommendations, and goals.

Querying the archive: AWS Glue and Athena

The sample implementation overlays an AWS Glue Data Catalog and an Athena workgroup on the Amazon S3 archive. Three external tables cover the full archive. The journals table uses Athena partition projection, and Hive-partitioned by agent space and date:

s3://<amzn-s3-demo-archive-bucket>/journals/space=<agent-space-id>/dt=2026-07-28/<execution-id>.json

Volume of recommendations is low (tens to hundreds of objects), so a flat external table over the recommendations/ prefix is sufficient. Athena recurses subdirectories by default, picking up every versioned snapshot.

The result bucket has Amazon S3 Object Lock but Object Lock prevents Athena from managing its own query-result objects. The query layer deploys a dedicated results bucket with a seven-day lifecycle rule for ephemeral query outputs.

Access control

Use IAM to control access. Investigation journals contain the agent’s full reasoning about your infrastructure. Scope your IAM permissions on the Athena workgroup, AWS Glue database, and on the archive bucket itself since bucket read access bypasses Athena entirely. Scope all three to your audit and operations teams.

To find all findings from the past 7 days for a specific resource:

SELECT
  execution_id,
  event_time,
  task.title,
  record.content
FROM devops_agent_audit.journals
CROSS JOIN UNNEST(journal_records) AS t(record)
WHERE dt >= date_format(current_date - interval '7' day, '%Y-%m-%d')
  AND record.recordType IN ('finding', 'investigation_result')
  AND record.content LIKE '%sg-0123456789abcdef0%'
ORDER BY event_time DESC;

The Athena workgroup integrates with Amazon Quick or any business intelligence tool that speaks JDBC/ODBC. Additional examples are available in the sample repository.

Closing the loop: Correlating findings to actual changes

The capture layers record what the agent found and what it recommended. But did the recommended fix actually land? This requires connecting the agent’s output to the real infrastructure change that followed.

The sample implementation includes correlate.py, an on-demand operator CLI that takes an archived finding or recommendation, resolves the resource it references, and reports what changed, when, and who did it. The correlation is heuristic by looking at resource identity and a tight time window in minutes to produce reliable attribution. This is why the sample implementation pairs it with a deterministic engine for agent-initiated actions.

It works by pivoting through two services:

  1. AWS Config resolves the resource identity by using select-resource-config, then pulls its configuration timeline from get-resource-config-history. This shows the before/after state of the resource around the time of the agent’s finding.
  2. CloudTrail looks up the write event that caused the change: who called what API, from where, and when. This attributes the change to a principal.

The output is a correlated record: the agent found X, the resource changed from state A to state B, and that change was made by principal Y at time T.

Because CloudTrail indexes resources by different identifiers depending on the service, you require a strategy registry. Examples are in the following table:

Resource type How CloudTrail indexes it Lookup strategy
S3 bucket Bucket name By name
Lambda function Function name By name
Amazon Relational Database Service (Amazon RDS) instance/cluster Full ARN (not the DB ID) Build ARN from template
Amazon Elastic Compute Cloud (Amazon EC2) security group Group ID as ResourceName By name, with a resource-type scan as fallback

A naive “look up by resource name” works for Amazon S3 and Lambda but returns zero results for Amazon RDS (RDS). The strategy registry encodes the right ID per resource type.

Correlating agent actions

When an operator approves an elevated action, the service stamps the approval ID into the credential it mints, so the executed call carries that ID inside its own principal ARN (op.system.apr.<approvalId>). The sample implementation includes correlate_agent.py that uses this. Because the ID is present on both sides, the correlation is a join. The engine checks the executed call against the argumentPins the operator was shown at approval time, so you can prove the agent’s behavior.

. correlate.py correlate_agent.py
Pivots on A resource the agent named Agent’s approval ID
Correlation heuristic deterministic
Answers Who changed? Who approved, and did it match?
Dependency CloudTrail and AWS Config CloudTrail

Production considerations

Understand the data volume. Journal size scales with investigation complexity. As an example:

Scenario Journal size API calls (pagination) Notes
Minimal (single-service, shallow investigation) ~65 KB 2–3 pages Quick symptom to finding arc
Typical (multi-signal, 1–2 findings) 250–340 KB 65–106 calls Typical investigations
Exhaustive (account-wide, high-priority) ~428 KB 150+ calls Full cross-service correlation

At 100 investigations/month at 300 KB average, you are storing roughly 30 MB/month of journal data.

Concurrency per agent space. By default, you can run three concurrent investigations per agent space. Additional requests queue as PENDING_START and start when a slot opens. The archival pipeline is unaffected because each terminal event triggers its own Lambda invocation. Refer to the AWS DevOps Agent Quotas page for future updates.

Paginate the journal. The journal API is server-paginated: pass limit, follow nextToken until it’s empty. A real incident’s journal can span several pages. Always loop.

Design for at-least-once delivery. Amazon EventBridge can deliver an event more than once. Key the Amazon S3 object on execution_id so a redelivery overwrites rather than duplicates, and attach an Amazon Simple Queue Service (Amazon SQS) dead-letter queue (DLQ) so a dropped terminal event is not lost.

Deploy per AWS Region and per account. Events land on the default bus in each Agent Space’s hosting account and Region. If you run agent spaces in multiple accounts, you must aggregate events to a central monitoring account for unified visibility. Refer to Amazon EventBridge cross-account document for further details.

Make the archive immutable. Enable Amazon S3 Object Lock and versioning. The sample implementation defaults to GOVERNANCE mode but for stronger compliance posture, use COMPLIANCE mode.

Warning: COMPLIANCE mode is irreversible. After it’s set, no principal (including the account root user) can delete or modify locked objects before their retention period expires. The only way out is closing the AWS account, and Object Lock itself can’t be disabled once enabled. Choose COMPLIANCE mode deliberately. If you use GOVERNANCE mode, enable CloudTrail data events on the bucket.

Encrypt your data. The sample implementation uses SSE-S3. If your compliance framework requires you to control and audit decryption events, use SSE-KMS with customer managed key.

The full loop

Here’s what a complete audit trail looks like for a single incident through resolution.

Step 1: Investigation. The agent investigates a failing Lambda function, concludes its security group restricts necessary egress, and writes the finding to the journal. Layer 2 archives the journal to Amazon S3.

Step 2: Recommendation. On its goal cadence, the agent generates a recommendation: “Update the security group egress rules to allow…” Layer 3 polls and captures it as recommendations/rec-a1b2c3.../v1.json with status PROPOSED. A later poll captures v2.json as the status changes.

Step 3: Engineer applies the fix. An engineer runs the suggested command. AWS Config records the new configuration item, and CloudTrail records the API call with principal, source IP, and timestamp.

Step 4: Correlation.

$ python correlate.py --archive-bucket $BUCKET \
    --recommendation rec-a1b2c3d4-5e6f-7890-abcd-ef1234567890 \
    --window-hours 24

Recommendation: rec-a1b2c3d4-5e6f-7890-abcd-ef1234567890
Title:          Update the Lambda security group egress rules to allow API access
Status:         PROPOSED → UPDATE_IN_PROGRESS (v2)

AWS Config change detected:

  Resource:     AWS::EC2::SecurityGroup / sg-0123456789abcdef0
  Changed:      2026-07-23 08:45:54.105000-04:00
CloudTrail attribution:
  Event:        AuthorizeSecurityGroupEgress
  Principal:    arn:aws:iam::111122223333:user/jsmith
  Source IP:    203.0.113.10
  Time:         2026-07-23 08:44:33-04:00

Correlation:    OK Recommendation → AWS Config change → CloudTrail event aligned

The agent found the problem, recommended the fix, and you can prove who applied it and when.

Step 5: A new investigation. A later investigation examines the same Lambda function, still erroring. The agent compares new advice against advice it has already given, and that comparison is semantic. But it compares against the recommendations currently attached to the goal, not against everything it has ever advised, and when the comparison is uncertain it keeps the two separate. Older advice drops out of that comparison set over time. Because you archived every recommendation and every finding with their resource identifiers, you can now compare across the full history:

$ python correlate.py --archive-bucket $BUCKET \
    --finding  exe-ops1-0f1e2d3c-4b5a-6978-8796-a5b4c3d2e1f0 \
    --check-prior-recommendations

Resource:       AWS::EC2::SecurityGroup /  sg-0123456789abcdef0

Prior recommendations referencing this resource:
   rec-a1b2c3d4-5e6f-7890-abcd-ef1234567890 (v2, UPDATE_IN_PROGRESS):
    "Update the security group egress rules..."
   rec-b2c3d4e5-6f70-8901-bcde-f01234567890 (v1, PROPOSED):
    "Update the security group egress rules..."

! This finding may be a consequence of recommendation(s): rec-a1b2c3d4-5e6f-7890-abcd-ef1234567890, rec-b2c3d4e5-6f70-8901-bcde-f01234567890
Last change to this resource (CloudTrail): Event: AuthorizeSecurityGroupEgress Principal: arn:aws:iam::111122223333:user/jsmith Source IP: 203.0.113.10 Time: 2026-07-23 08:44:33-04:00

The archive diagnosed the cause of the cause. Two recommendations, raised separately, on one resource, in one view. The agent’s own comparison covers the advice currently attached to the goal. The archive covers all of it. That is the feedback loop the audit trail adds.

Agent Actions changes Step 3’s actor, and the agent applies the fix directly. In the recommendation path, the human runs the command. In the elevated-action path, the human approves a specific call, and the agent executes it under a single-use session. correlate_agent.py uses a single-use session named for the approval (op.system.apr.<approvalId>), with invokedBy: aidevops.amazonaws.com rather than a time-window heuristic.

Operating the pipeline: Common failures

Always design for failure. Here are some common failures and how to detect and recover.

Failure Symptom Detection Recovery
Lambda timeout No archive in Amazon S3. Event in DLQ DLQ ApproximateNumberOfMessagesVisible alarm Increase timeout above the 2-minute default. Replay DLQ message which is idempotent on the execution_id key
Missed recommendation poll Gap in recommendations/ prefix with a version number skipped Periodic reconciliation: compare Amazon S3 keys against list-recommendations response Re-run poll Lambda manually (idempotent)
Amazon EventBridge delivery failure Missing lifecycle event in Layer 1 logs Layer 2 archive exists without matching Layer 1 log entry No data loss since journal already archived. Gap is in lifecycle visibility only
Amazon S3 write failure Lambda errors spike. DLQ grows Lambda error rate metric and DLQ alarm Fix IAM/bucket policy. Replay DLQ (all messages are idempotent)
AWS Config recorder stopped correlate.py returns no configuration history AWS Config recorder status alarm Re-enable recorder. Note: historical gap is permanent for the stopped period
Journal API throttled Partial archive. Lambda retries exhaust timeout Lambda error logs showing throttling exceptions Implement exponential backoff in the pagination loop. Increase timeout
Approval recorded but not executing Approval exists in CloudTrail with no corresponding write Join approvals to execution on the approval ID None needed

The highest value alarm is on the DLQ message count. A non-empty DLQ means a terminal event triggered, but the journal was not archived. Terminal events aren’t re-emitted, and the DLQ retains messages for 14 days. After that, the record is lost. The sample implementation ships this alarm at a threshold of 1, wired to an Amazon Simple Notification Service topic.

Run a reconciliation check weekly or monthly. Compare the execution_id values in the Layer 1 lifecycle log against the set of keys in the Amazon S3 journals/ prefix. Any ID in the logs but not in Amazon S3 represents a missed archive.

Limitations

Automated correlation – The current design requires a human to run correlate.py. Extend to a Lambda function that triggers on each new journal archive, cross-references the finding’s resource identifiers against the recommendations table, and alerts when a new finding touches a resource that was the subject of a prior recommendation.

Schema evolution – The Athena table definitions depend on the journal’s recordType values and content structure. If new record types appear, queries can return incomplete results without raising an error. Monitor for unknown recordType values. A query that returns zero findings for a week of active investigations is a signal that the schema moved.

Conclusion

Adopting an autonomous agent is a trust decision, and trust needs evidence. AWS DevOps Agent gives you the raw material: a journal of its reasoning, a real-time lifecycle event stream, a control-plane audit in CloudTrail, and an action boundary you can read straight from IAM. The pattern in this post assembles those into a durable, low-maintenance audit trail using services you already run.

The archive is more than compliance paperwork. With a persistent record of every finding and every recommendation, you can correlate across investigations and recommendations the agent no longer has in view, and against the present state of your infrastructure. That feedback loop is the difference between trusting the agent and understanding it.

Start with Layer 1. A single Amazon EventBridge rule to a log group gives you visibility into every investigation within minutes. Add the journal-archiving Lambda when you are ready to retain the agent’s decisions for the long term. Add the correlation layer when you want to prove that recommendations were acted on and catch the ones that created new problems.

Clone the sample repo to get started. It covers prerequisites, deploy steps, codebases, and teardown instruction. If you want the agent’s mitigations to become code, Automated incident remediation with AWS DevOps Agent and Kiro CLI builds a pipeline.


About the authors

Ben Peterson

Ben Peterson

Ben is a Senior Solutions Architect at AWS, focused on the developer experience and helping ISV customers modernize on AWS. He provides strategic guidance on using the AWS suite of services to modernize legacy systems, optimize performance, and unlock new capabilities. Connect with Ben on LinkedIn.

Jake Izumi

Jake Izumi

Jake is a Senior Solutions Architect supporting the NAMER ISV customers at AWS. Using his previous experience supporting corporate growth strategies, Jake works with business and technology leaders to innovate and grow on top of AWS. Connect with Jake on LinkedIn.

Sean Falconer

Sean Falconer

Sean is a Senior Solutions Architect at AWS, focused on agentic AI and event-driven architectures for ISV customers. His current work centers on the trust and governance patterns that let teams adopt autonomous agents in production. Connect with Sean on LinkedIn.

Best practices for scaling large consumer groups on Amazon MSK

Post Syndicated from Pallavi Jha original https://aws.amazon.com/blogs/big-data/best-practices-for-scaling-large-consumer-groups-on-amazon-msk/

When scaling large consumer groups on Amazon Managed Streaming for Apache Kafka (Amazon MSK), a common challenge is managing the size of internal metadata records. During rebalances, Kafka persists a metadata record to the internal __consumer_offsets topic. If the consumer group is large enough, this record can exceed the default 1 MB limit. This causes a RecordTooLargeException and a rebalance retry loop.

In this post, we explain how consumer group metadata grows and how to estimate your metadata size. We provide a step-by-step walkthrough for increasing the topic-level size limit (the most common remediation), along with guidance on three complementary strategies: splitting groups, right-sizing partitions, and optimizing naming conventions. We also discuss capacity planning, monitoring, and how KIP-848 in Apache Kafka 4.0 addresses this constraint at the protocol level.

Prerequisites: This post assumes familiarity with Apache Kafka consumer groups, rebalance protocols, and Amazon MSK cluster configuration. You should have access to the kafka-configs.sh CLI tool or the Amazon MSK console. The configuration approaches described apply to Amazon MSK Provisioned clusters with Standard brokers. The KIP-848 section covers a forward-looking protocol change in Apache Kafka 4.0 that applies across deployment types.

How consumer group metadata grows

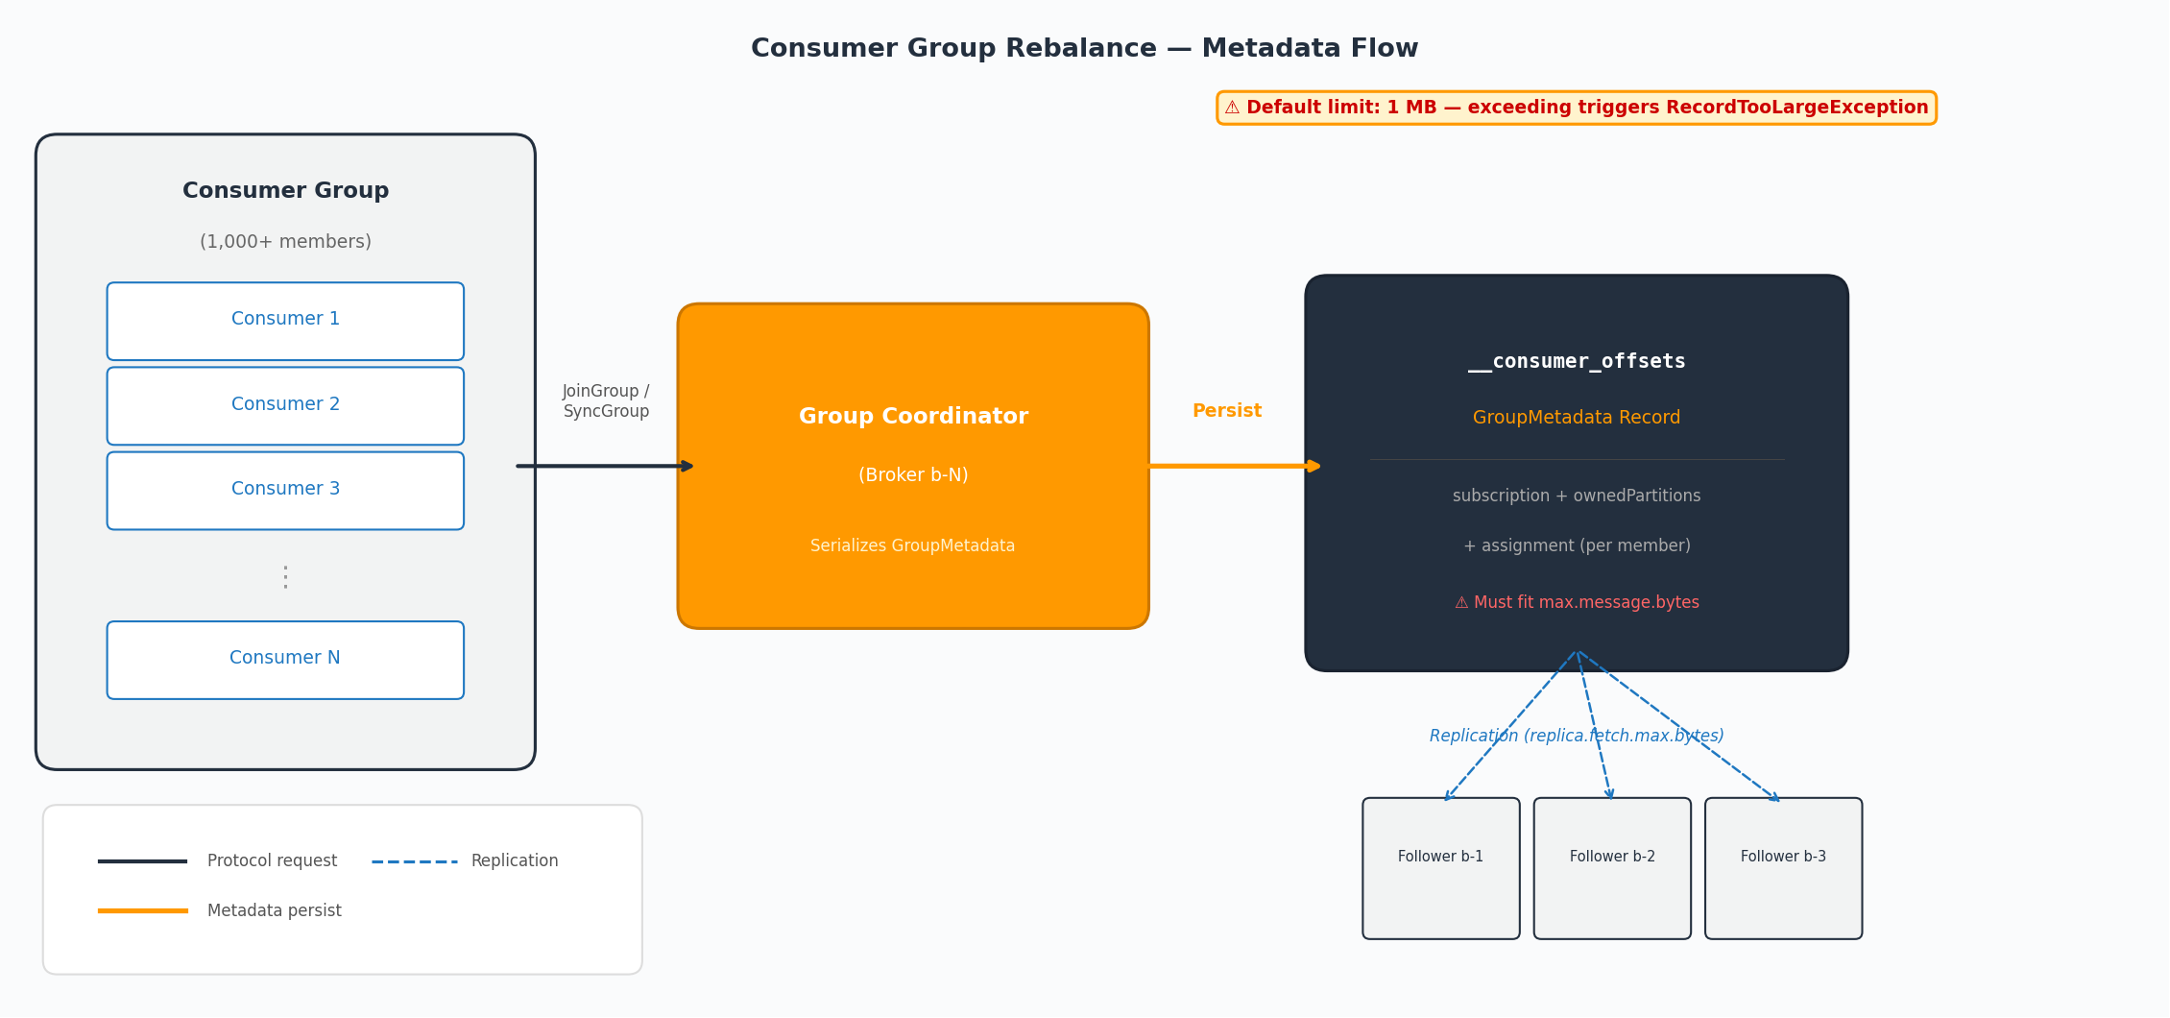
The following diagram illustrates how consumer group metadata flows through the system during a rebalance:

Flow of a GroupMetadata record from the Group Coordinator to the internal offsets topic and follower brokers during a rebalance

Figure 1: Consumer group metadata flow during a rebalance

During a rebalance, the Group Coordinator serializes a GroupMetadata record containing information about every member in the group and persists it to the __consumer_offsets topic. This record must fit within the topic’s max.message.bytes limit. Follower brokers must also replicate it, constrained by replica.fetch.max.bytes. For each member, the record includes:

  • Subscription topics – The list of topics the member subscribes to.
  • Owned partitions – Partitions currently held by the member.
  • Assignment – The new partition assignment after rebalancing.
  • Client ID – The configured client.id.

Apache Kafka’s serialization format repeats topic names multiple times per member: once in subscription, once in ownedPartitions, and once in assignment. The client.id adds further per-member overhead. The broker stores these metadata records uncompressed in __consumer_offsets.

Estimating your metadata record size

You can approximate your consumer group’s metadata record size with the following formula:

record_size ≈ member_count × (3 × avg_topic_name_bytes + 2 × client_id_bytes + ~200 bytes overhead)

Example: A group with 1,000 members, a 50-byte topic name, and a 40-byte client ID:

1,000 × (150 + 80 + 200) = ~430 KB

At 1,500 members with the same parameters: ~645 KB. With multiple topic subscriptions or longer naming conventions, the record can exceed 1 MB well before 2,000 members.

Approaches to handle large consumer group metadata

The following sections describe four strategies for managing large consumer group metadata, starting with the most direct remediation.

Increase max.message.bytes on __consumer_offsets

If your consumer group metadata exceeds 1 MB, you can increase the maximum record size on the internal topic. This is the most direct path to help unblock consumer groups that have already scaled beyond the default. Note that max.message.bytes is the topic-level configuration name, while message.max.bytes is the equivalent broker-level default.

1. Update the topic-level configuration:

kafka-configs.sh --bootstrap-server <bootstrap-server> \
    --entity-type topics \
    --entity-name __consumer_offsets \
    --alter \
    --add-config max.message.bytes=2097152 # topic-level config for max record size

2. Update replica.fetch.max.bytes at the cluster level:

This broker-level setting controls the maximum fetch size for inter-broker replication. Set it equal to or greater than max.message.bytes on __consumer_offsets so follower brokers can replicate large metadata records.

replica.fetch.max.bytes=2097152

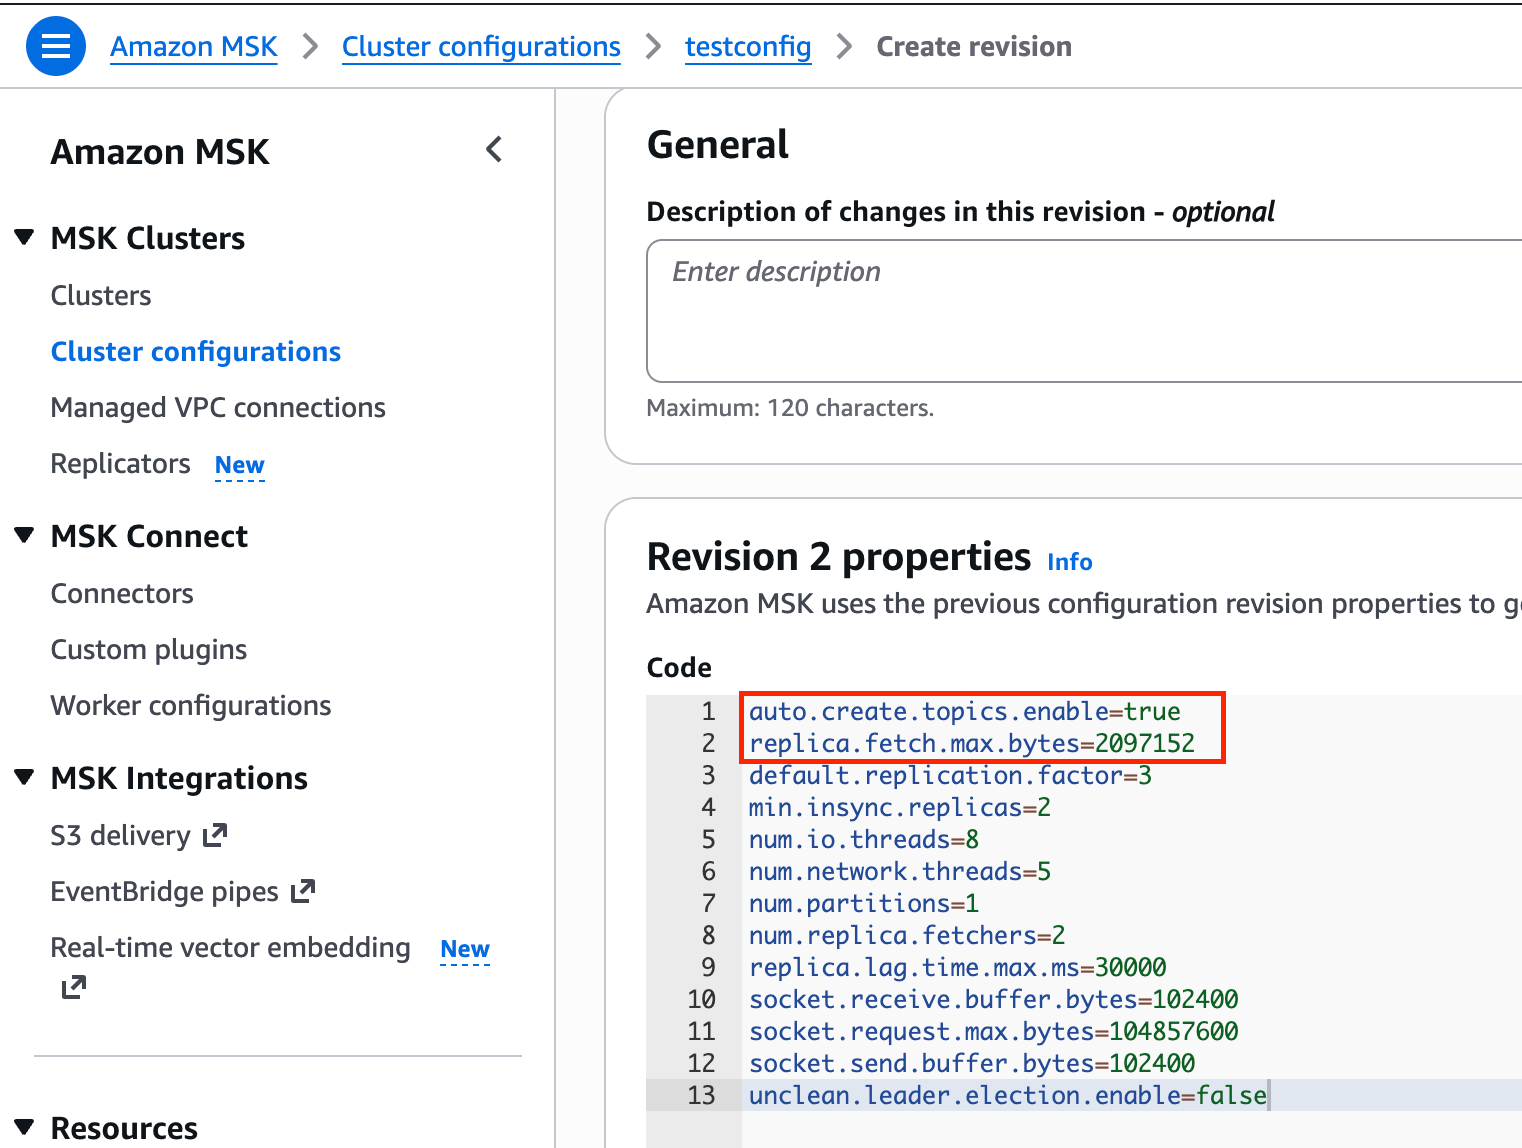
You can apply this through the Amazon MSK console under Cluster configuration or using the AWS Command Line Interface (AWS CLI) with update-cluster-configuration.

Amazon MSK console cluster configuration editor with the replica.fetch.max.bytes property set

Figure 2: Setting replica.fetch.max.bytes in the Amazon MSK cluster configuration console

Important: Always make sure that replica.fetch.max.bytes ≥ max.message.bytes for __consumer_offsets. Without this, you might observe UnderReplicatedPartitions on the internal topic.

3. Test in a non-production environment first:

  • Trigger a consumer group rebalance (restart consumers or scale the group).
  • Verify no RecordTooLargeException in broker logs.
  • Confirm broker heap usage and replication lag remain healthy.

Split large consumer groups

Breaking a single large consumer group into multiple smaller groups reduces the per-group metadata record size proportionally. To split a group, deploy multiple connector or consumer instances, each with a distinct group.id, subscribing to the same topic but consuming from a subset of partitions. The system preserves offset tracking within each sub-group independently.

When to use: Consumer group membership is growing unboundedly through Auto Scaling, and you want to keep each group’s metadata well within limits without modifying internal topic configuration.

Trade-off: Increases operational complexity. You have multiple groups to monitor and manage instead of one.

Right-size partition count and auto scaling bounds

Over-partitioned topics require more consumers to fully parallelize, which inflates group membership. Unbounded auto scaling policies can grow consumer groups beyond what was originally planned.

  • Review whether your topic’s partition count matches your actual throughput requirements.
  • Configure auto scaling policies with an upper bound on consumer replicas (for example, Horizontal Pod Autoscaler on Amazon Elastic Kubernetes Service (Amazon EKS)).
  • Align partition count with the maximum number of consumers you intend to support.

This is a proactive measure, best applied during topic design and capacity planning to prevent the metadata size issue from occurring in the first place.

Optimize naming conventions

Consumer group names and client IDs contribute to the overall metadata size. Shorter, standardized naming reduces per-member overhead.

Considerations: Changing an active consumer group’s name means the new group starts with no committed offsets and all tracking history is lost. For this reason, naming optimization is most practical for new deployments rather than existing production groups.

Capacity planning for larger metadata records

When you increase max.message.bytes on __consumer_offsets, larger metadata records consume more broker heap during rebalance processing. Proper capacity planning helps you select the right broker instance type and configuration value before hitting production issues.

Planning steps:

  1. Calculate your current record size using: member_count × (3 × topic_name_bytes + 2 × client_id_bytes + ~200).
  2. Project peak membership based on your auto scaling upper bound (maximum consumer replicas × number of tasks per connector, if using Kafka Connect).
  3. Apply a 2× safety margin to account for protocol overhead, multi-topic subscriptions, and burst scaling events.
  4. Select your max.message.bytes value from the following guidance table.
  5. Choose your broker instance type based on heap requirements. Larger metadata records increase heap pressure during rebalances. For groups exceeding 1,000 members with 2+ MB metadata records, use kafka.m5.xlarge or larger to provide sufficient heap headroom.
  6. Validate in non-production by running a consumer group at projected peak membership and monitoring HeapMemoryAfterGC during rebalances.

The following table provides sizing guidance based on consumer group size:

Consumer Group Size Guidance
< 500 members Default 1 MB is typically sufficient. kafka.m5.large or larger.
500–1,000 members Monitor metadata size. Consider increasing to 2 MB. kafka.m5.xlarge or larger.
1,000–2,000 members Increase to 2–5 MB. kafka.m5.2xlarge or larger for adequate heap headroom.
> 2,000 members Combine increased limit with group splitting. kafka.m5.2xlarge minimum. Consider kafka.m5.4xlarge for high rebalance frequency.

Key metrics to monitor

The following Amazon CloudWatch metrics help you track consumer group metadata health:

Metric What it tells you
HeapMemoryAfterGC (Amazon CloudWatch) Percentage of heap memory in use after garbage collection. Indicates memory pressure from larger metadata records during rebalances.
UnderReplicatedPartitions (Amazon CloudWatch) Replication health. Non-zero may indicate replica.fetch.max.bytes is too low.
GC pause duration (broker logs) Prolonged GC can trigger session timeouts and cascading rebalances.
Consumer group rebalance rate Stable groups should not rebalance frequently after configuration changes.
Consumer lag Confirms consumers are making progress after rebalances complete.

We recommend creating two Amazon CloudWatch alarms for HeapMemoryAfterGC. Set a warning alarm at 60% to indicate potential performance degradation. Set a critical alarm at 80 percent, at which point you should scale brokers or reduce consumer group size. For UnderReplicatedPartitions, alarm at any value> 0 sustained for more than 5 minutes after a configuration change.

Looking ahead: KIP-848 and Apache Kafka 4.0

Apache Kafka 4.0 (released March 2025) adopted KIP-848 as the default consumer protocol. The broker now computes partition assignments server-side rather than delegating to a consumer group leader. Because each member no longer carries full subscription and assignment data on the wire, the new protocol reduces per-member metadata size. For details on the protocol changes that achieve this reduction, see the KIP-848 design document. KIP-848 also introduces incremental rebalances.

Newer Apache Kafka versions on Amazon MSK bring smaller metadata records by default. The following steps help you prepare for KIP-848 adoption:

  1. Track Amazon MSK version support for Apache Kafka 4.0+.
  2. Verify your Kafka client libraries support the new consumer protocol.
  3. Test the new protocol in a non-production environment before migrating production consumer groups.
  4. Plan for a phased rollout, starting with non-critical consumer groups.

Conclusion

The following table summarizes when to apply each approach. The max.message.bytes increase (covered step-by-step earlier) is the primary remediation. The other strategies are complementary guidance you can adapt to your environment:

Situation Recommended approach
Already hitting RecordTooLargeException in production Increase max.message.bytes on __consumer_offsets + set replica.fetch.max.bytes accordingly
Planning for growth Right-size partitions, set auto scaling bounds, monitor metadata size
Naming overhead is significant Optimize naming conventions for new deployments
Operating at very large scale (2,000+ members) Combine increased limits with consumer group splitting
Long-term architecture Plan migration path to KIP-848 (Apache Kafka 4.0)

Test configuration changes in non-production first, monitor broker metrics during and after rebalances, and scale incrementally. With these practices in place, you can operate consumer groups at the scale your streaming workloads require.

To get started:

  1. Review the Amazon MSK Developer Guide for cluster configuration steps.
  2. Use the sizing formula in this post to estimate your current metadata record size.
  3. Set up Amazon CloudWatch alarms on HeapMemoryAfterGC to monitor broker health proactively.


About the authors

Pallavi Jha

Pallavi Jha

Pallavi is a Technical Consultant at Amazon Web Services, helping customers architect and optimize their streaming workloads on Amazon MSK. She works with enterprises running large-scale data pipelines on Apache Kafka, focusing on performance, resilience, and operational best practices. Outside work, she enjoys exploring creating music and hiking. Connect with her on LinkedIn.

Sunil Kumar Patro

Sunil Kumar Patro

Sunil is a Senior Technical Account Manager at Amazon Web Services with over 21 years of experience driving architecture and delivery for multi-technology platforms. He works with global enterprise customers to build scalable, modern, and cost-effective solutions on AWS. He specializes in Amazon EKS, Amazon MSK, Amazon OpenSearch Service, and Data Lakehouse architectures, helping customers design high-performing, real-time streaming and analytics platforms at scale.

Discover and govern Snowflake data using SageMaker Unified Studio

Post Syndicated from Marco Duarte original https://aws.amazon.com/blogs/big-data/discover-and-govern-snowflake-data-using-sagemaker-unified-studio/

Many organizations operate in hybrid data environments where critical assets live in Snowflake while analytics workloads run on AWS, which can create governance gaps, discovery friction, and duplicated efforts when the two aren’t connected.

With Amazon SageMaker Unified Studio, you can govern data across Snowflake and AWS through its integrated catalog and AWS Glue Data Quality, a capability of AWS Glue. You connect directly to Snowflake tables without moving data, apply quality rules using AWS Glue Visual ETL, and publish validated assets to Amazon SageMaker Catalog, maintaining consistent governance across your entire distributed data estate.

Without this integration, cataloging Snowflake data requires building extraction pipelines, often taking days. With SageMaker Unified Studio connected to Snowflake, you can query, catalog, and validate the quality of federated data in 5–15 minutes. No data replication or custom ETL code required.

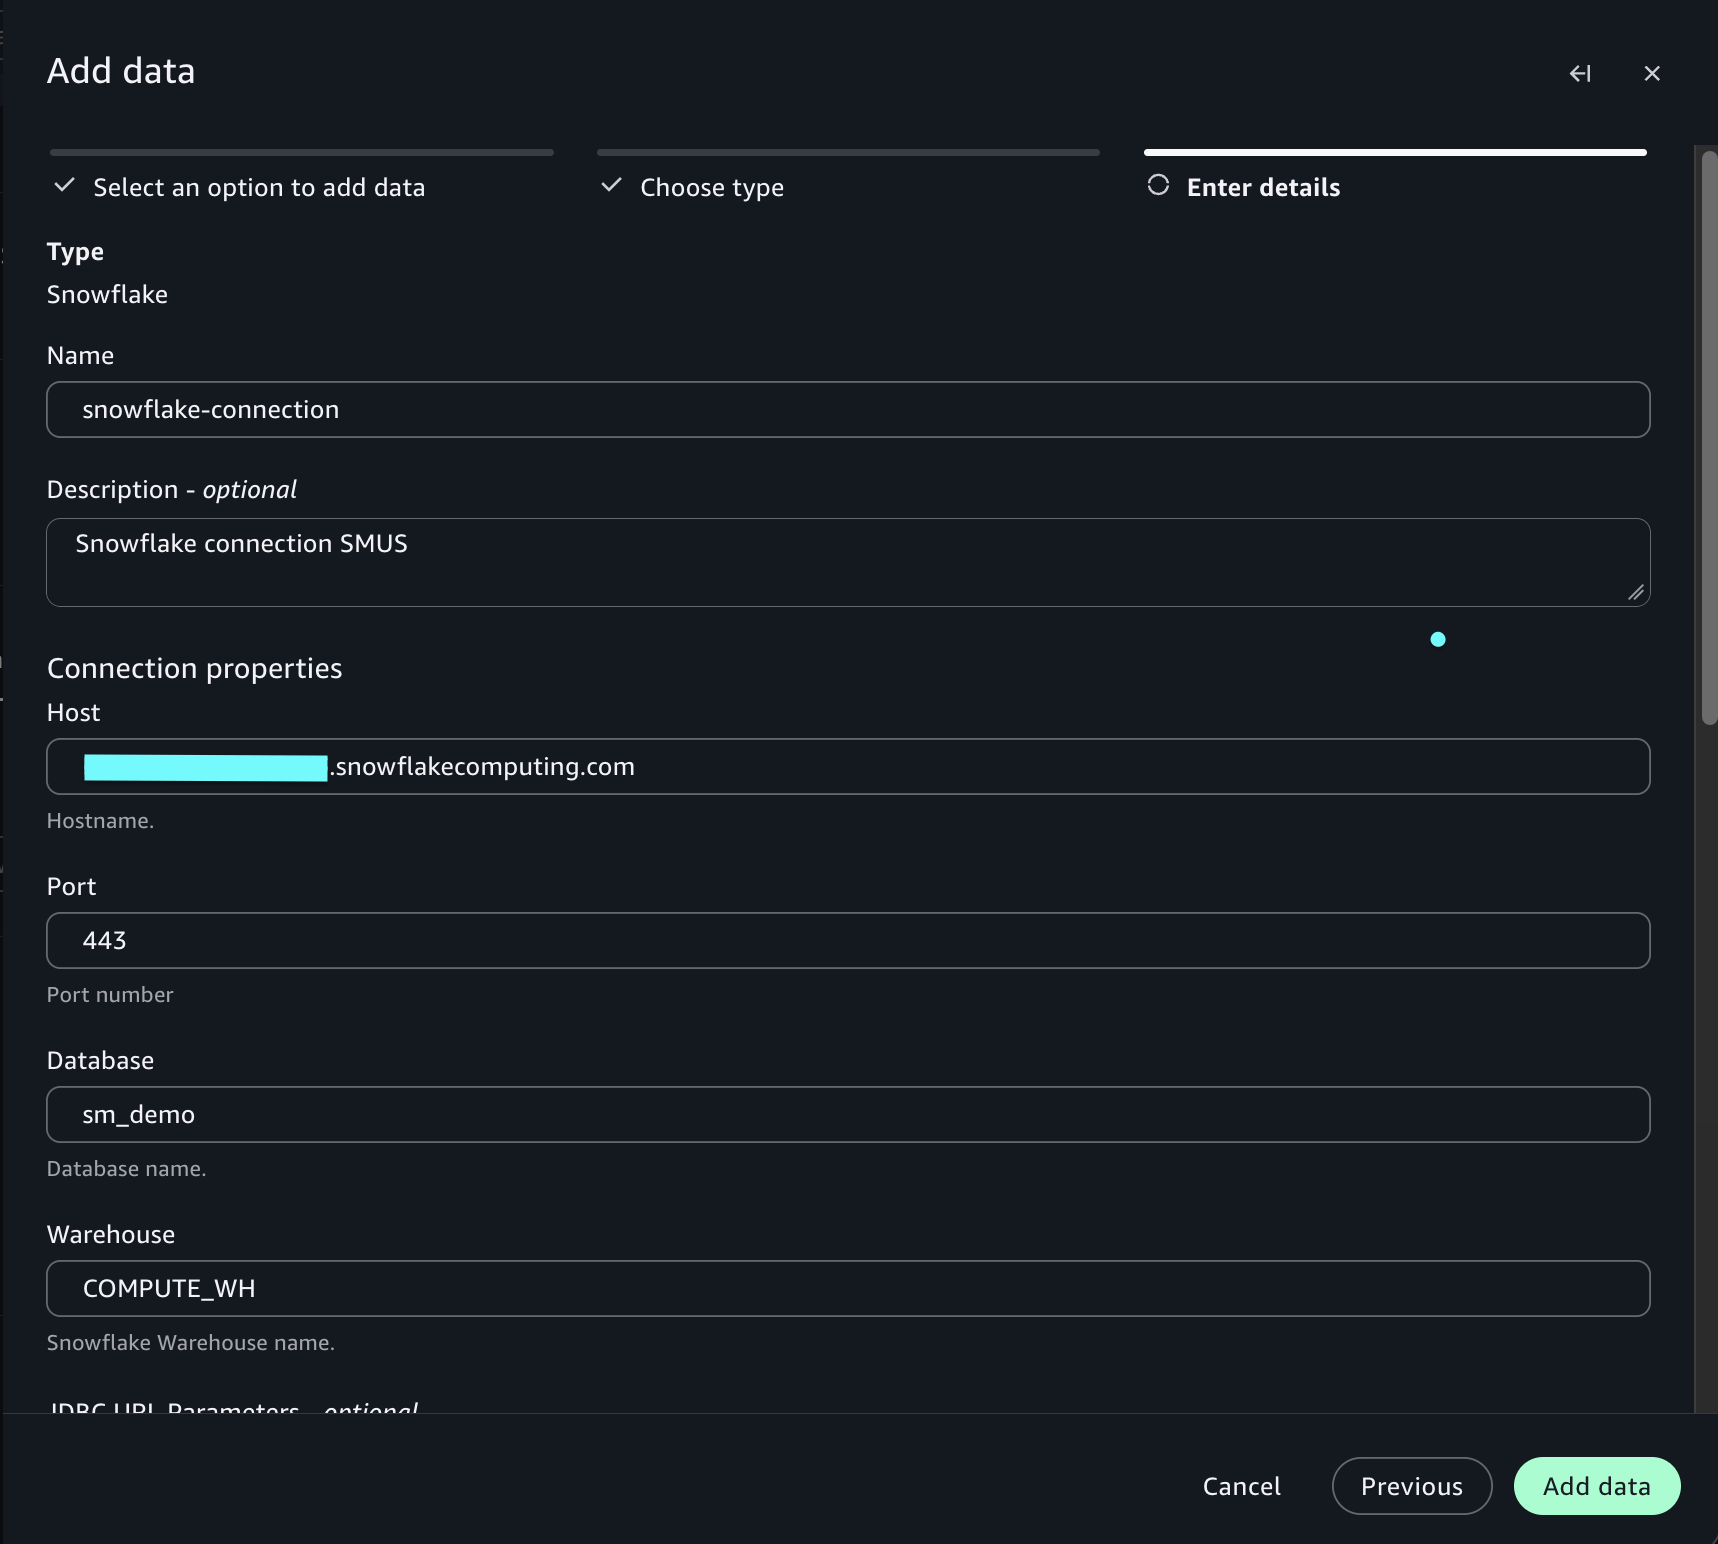
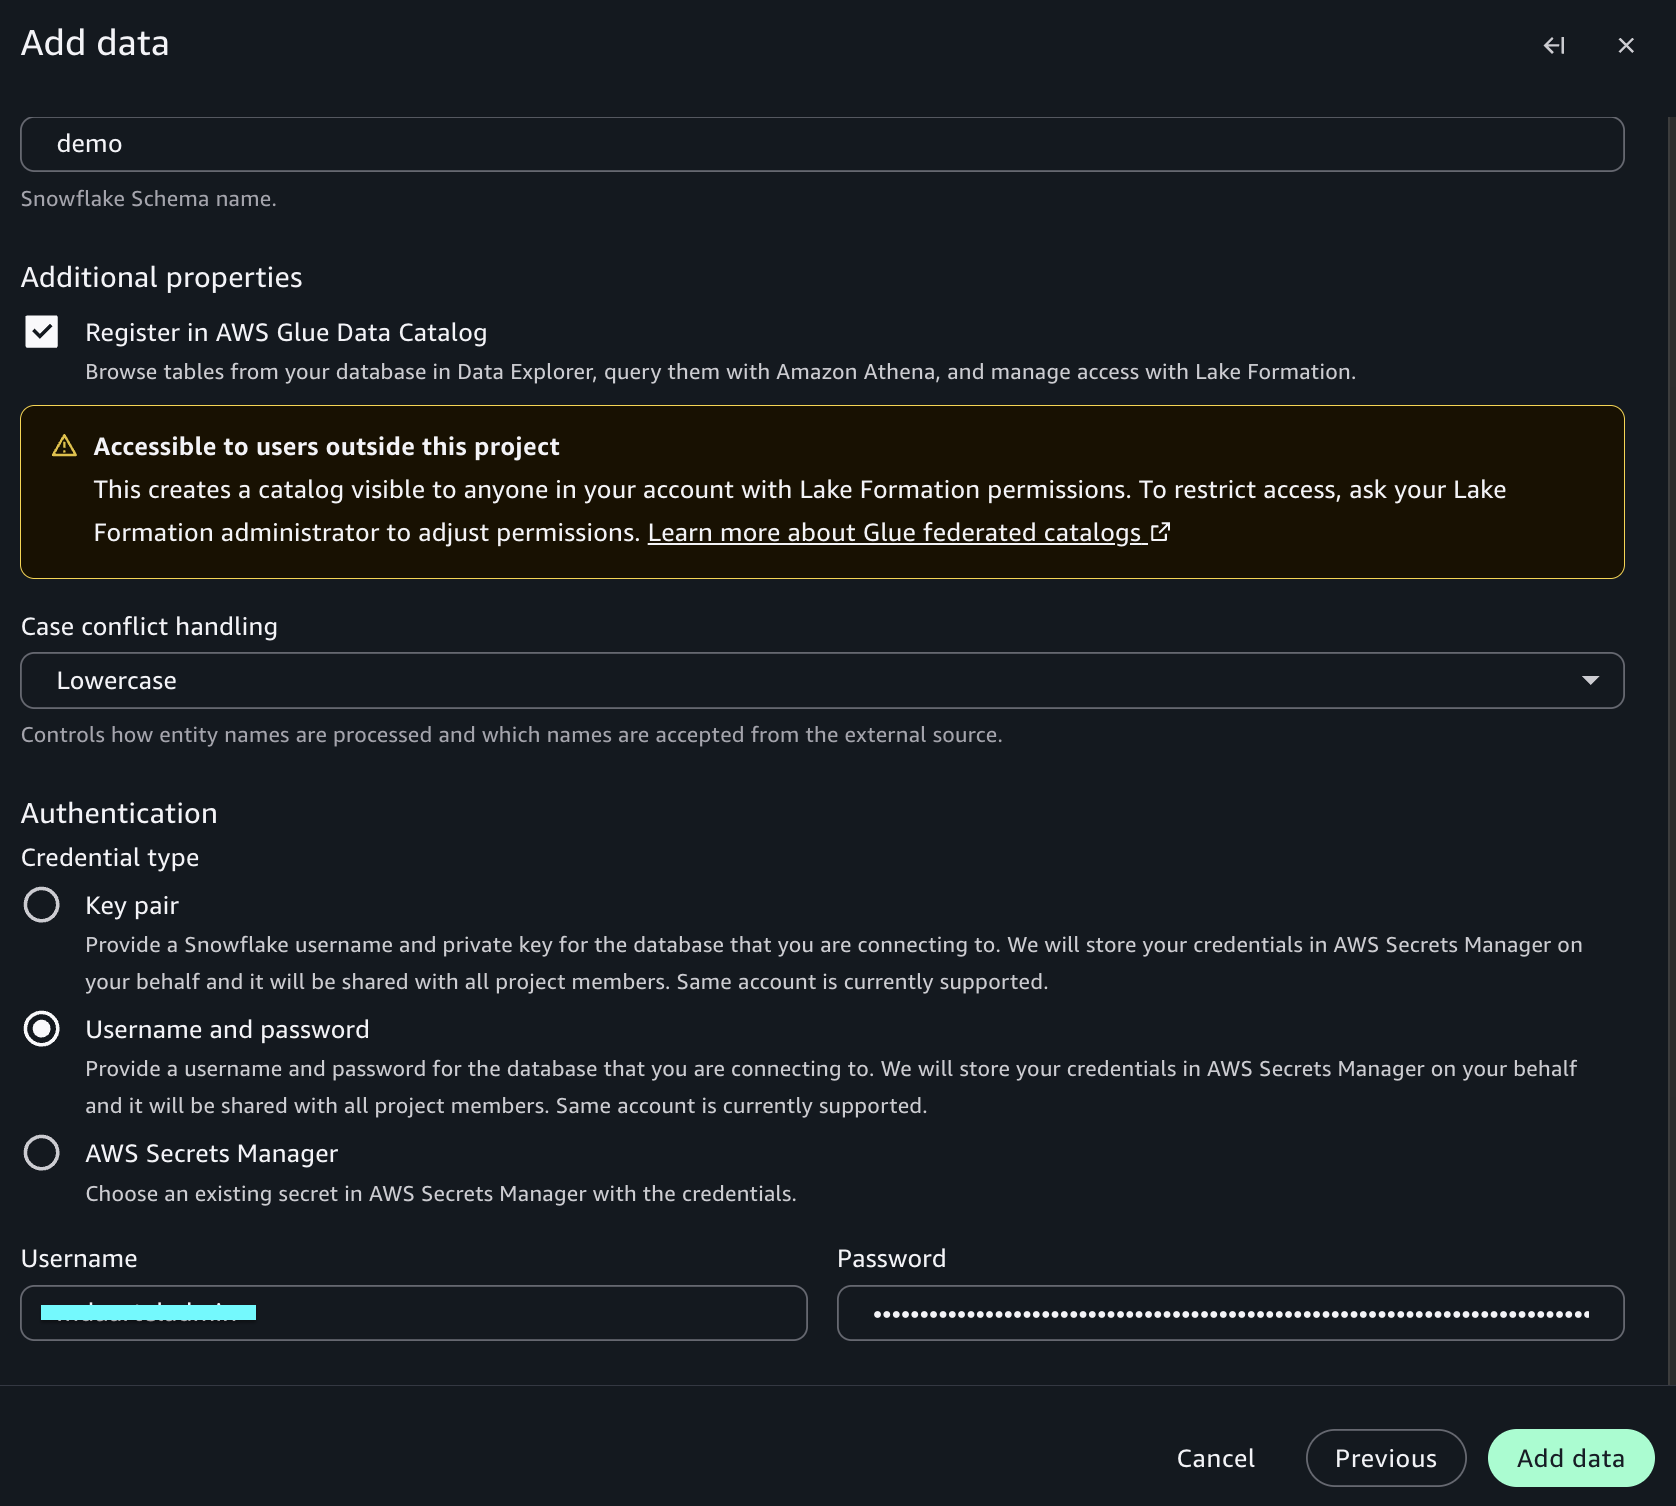
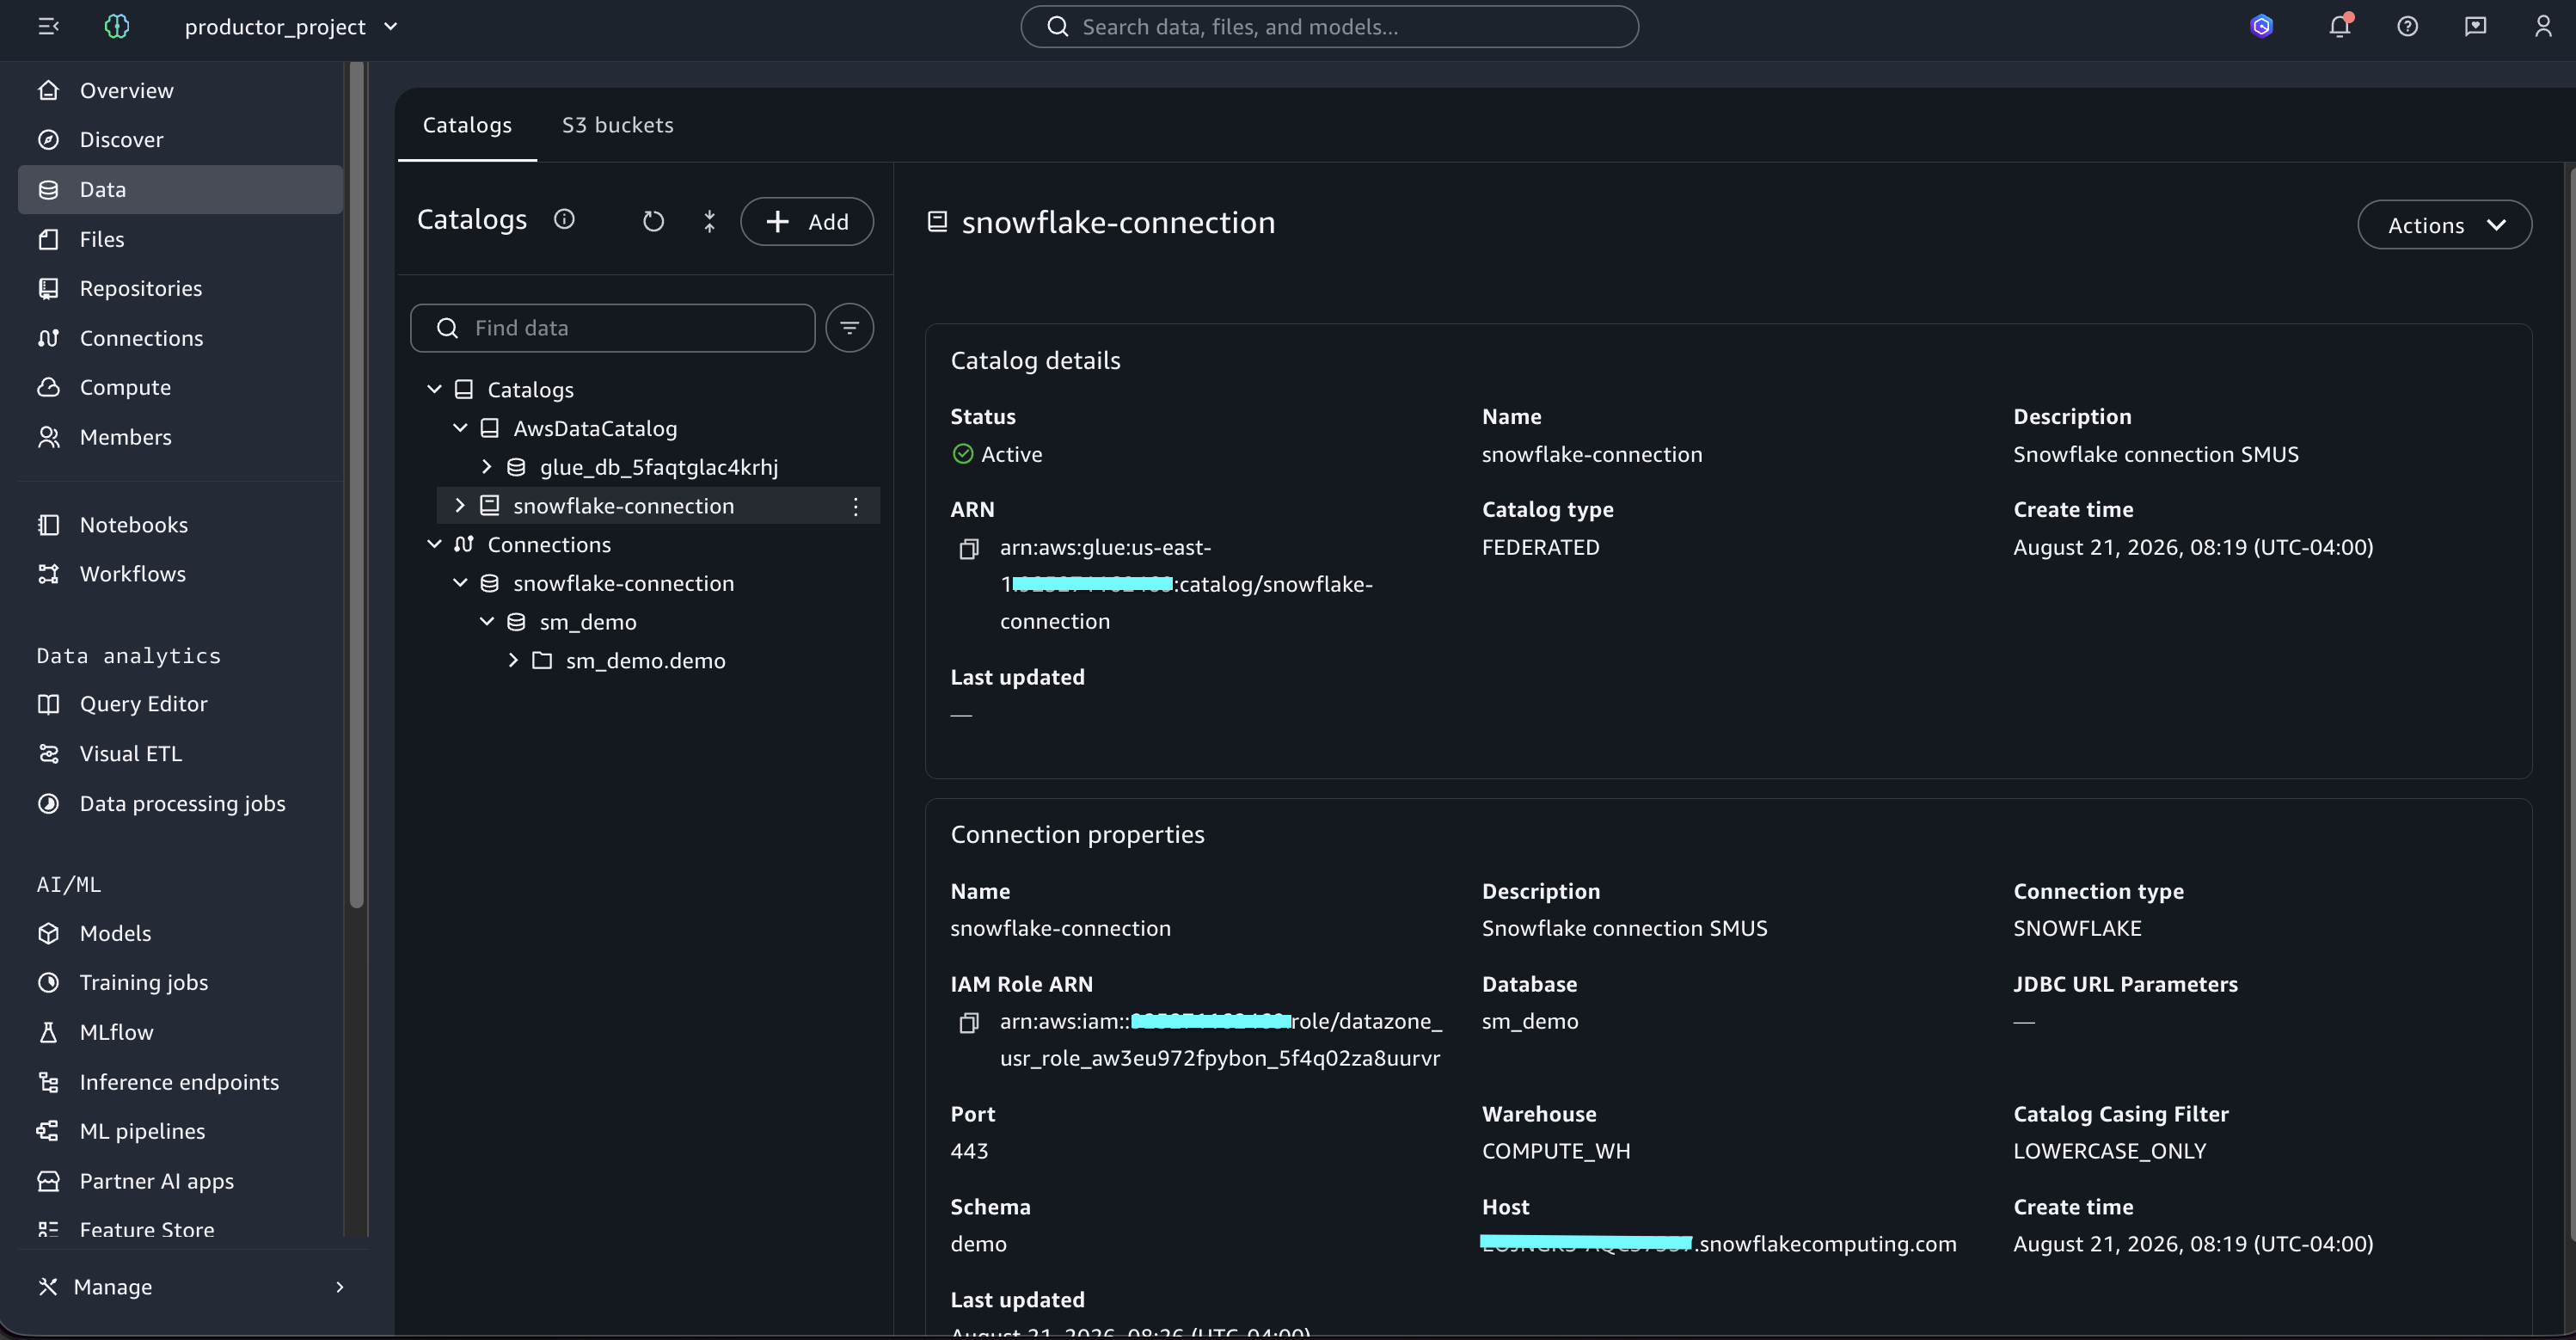
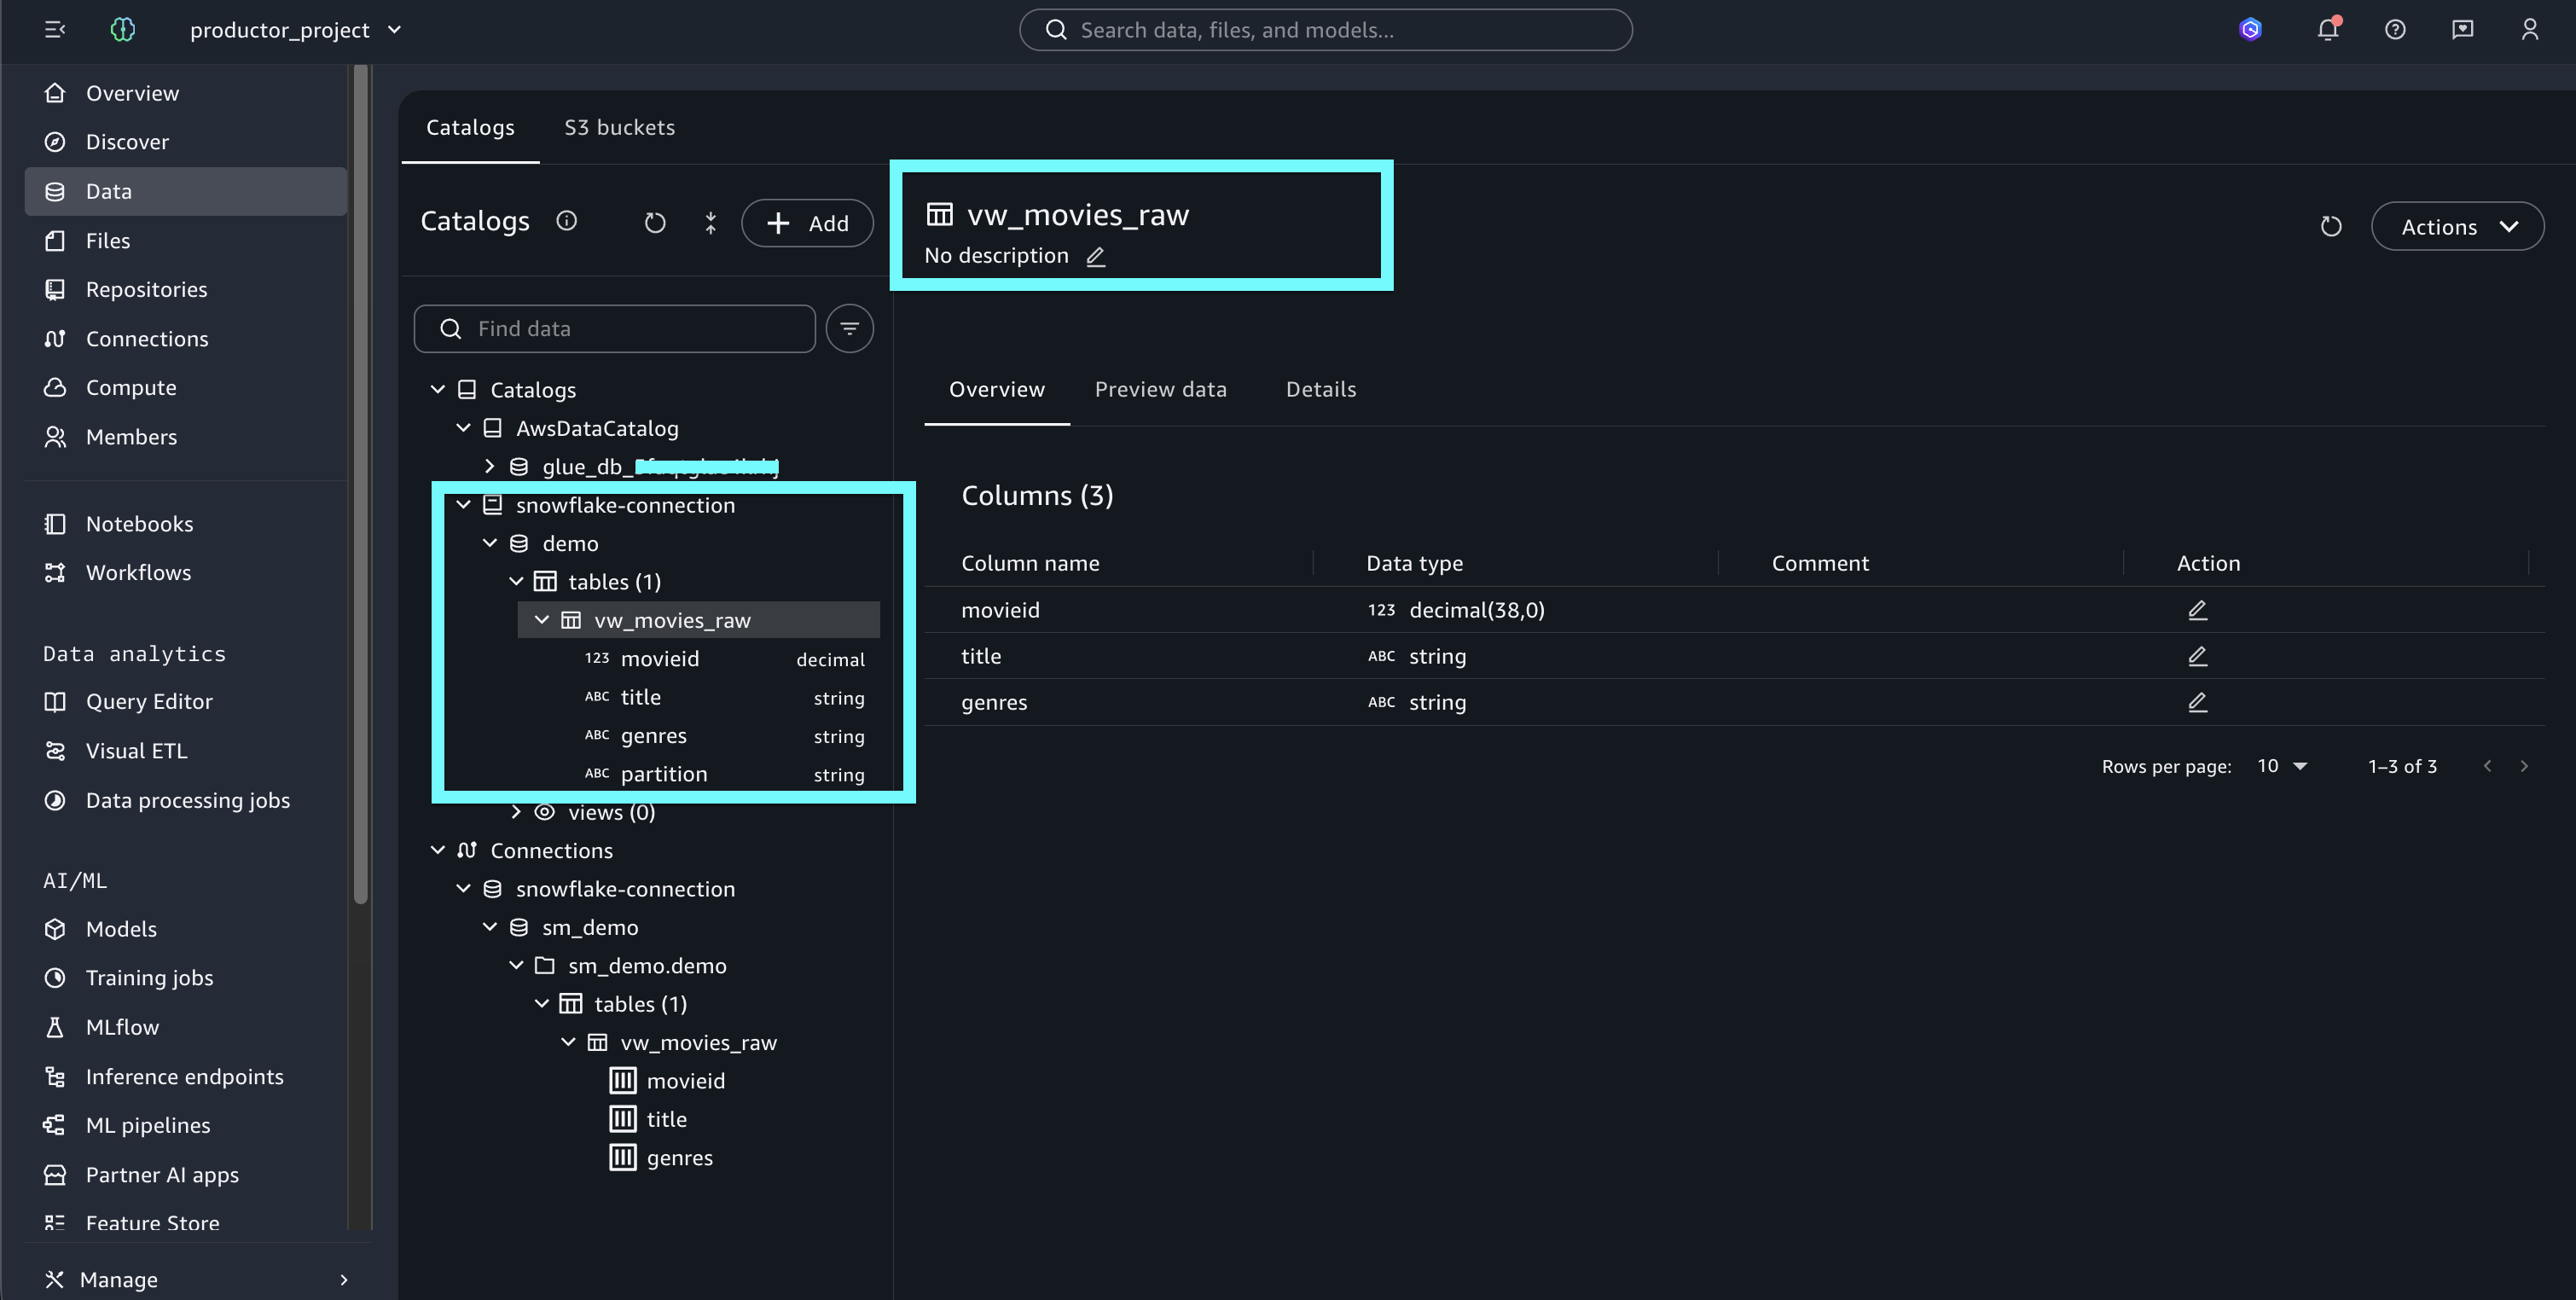
In this post, we show you how to connect Snowflake to Amazon SageMaker Unified Studio, register data assets in Amazon SageMaker Catalog, configure data quality validation using AWS Glue Visual ETL, and publish assets for unified collaboration. By following these steps, you enrich federated assets with data quality scores so that consumers across your organization can discover and trust the data, all while keeping it in Snowflake.

Solution overview

This solution integrates Snowflake with Amazon SageMaker Unified Studio for centralized data cataloging and quality validation.

The architecture uses an AWS Glue connection to federate the Snowflake catalog into Amazon SageMaker Unified Studio. Tables become available in the project catalog without complex storage configurations. You can query data directly using SQL analytics, publish datasets to Amazon SageMaker Catalog for organization-wide discovery, and apply data quality rules through AWS Glue Visual ETL pipelines.

The workflow consists of the following steps:

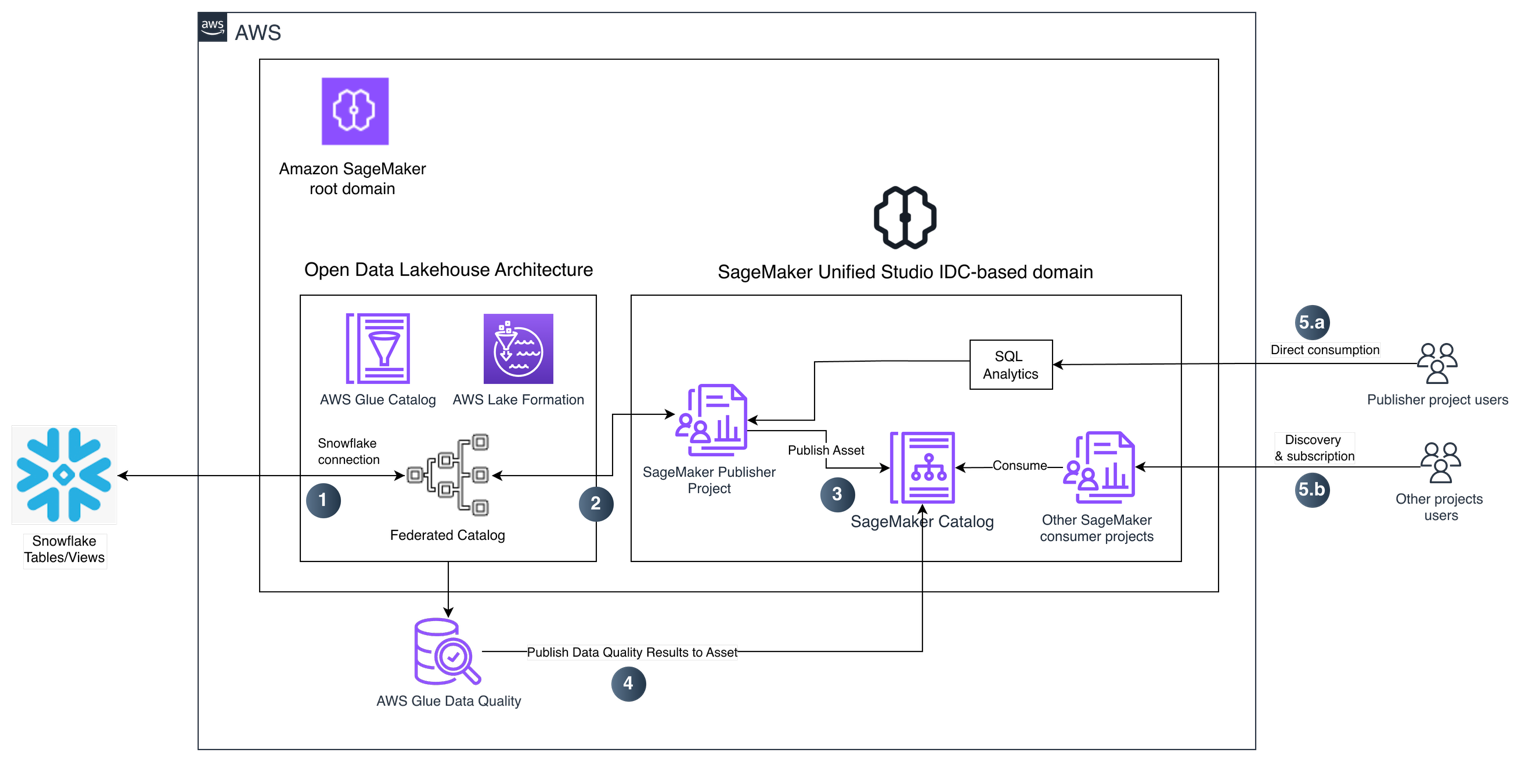
Architecture diagram: Snowflake federated into SageMaker Unified Studio through AWS Glue, with data quality validation and publishing to SageMaker Catalog

Figure 1: Architecture for federating Snowflake into SageMaker Unified Studio and validating data quality

  1. Snowflake connection creation on Amazon SageMaker Unified Studio — Amazon SageMaker Unified Studio uses an AWS Glue connection to federate Snowflake tables and views into its open data lakehouse architecture. The federated catalog entry is registered in AWS Glue Data Catalog and governed by AWS Lake Formation for centralized access control, without moving data out of Snowflake.
  2. Federate Snowflake tables into the Amazon SageMaker publisher project — The Amazon SageMaker publisher project discovers the federated Snowflake tables through the AWS Glue Data Catalog integration.
  3. Publish the dataset to Amazon SageMaker Catalog — The publisher project publishes the dataset as a governed asset to the Amazon SageMaker Catalog, making it discoverable for data consumers across the organization.
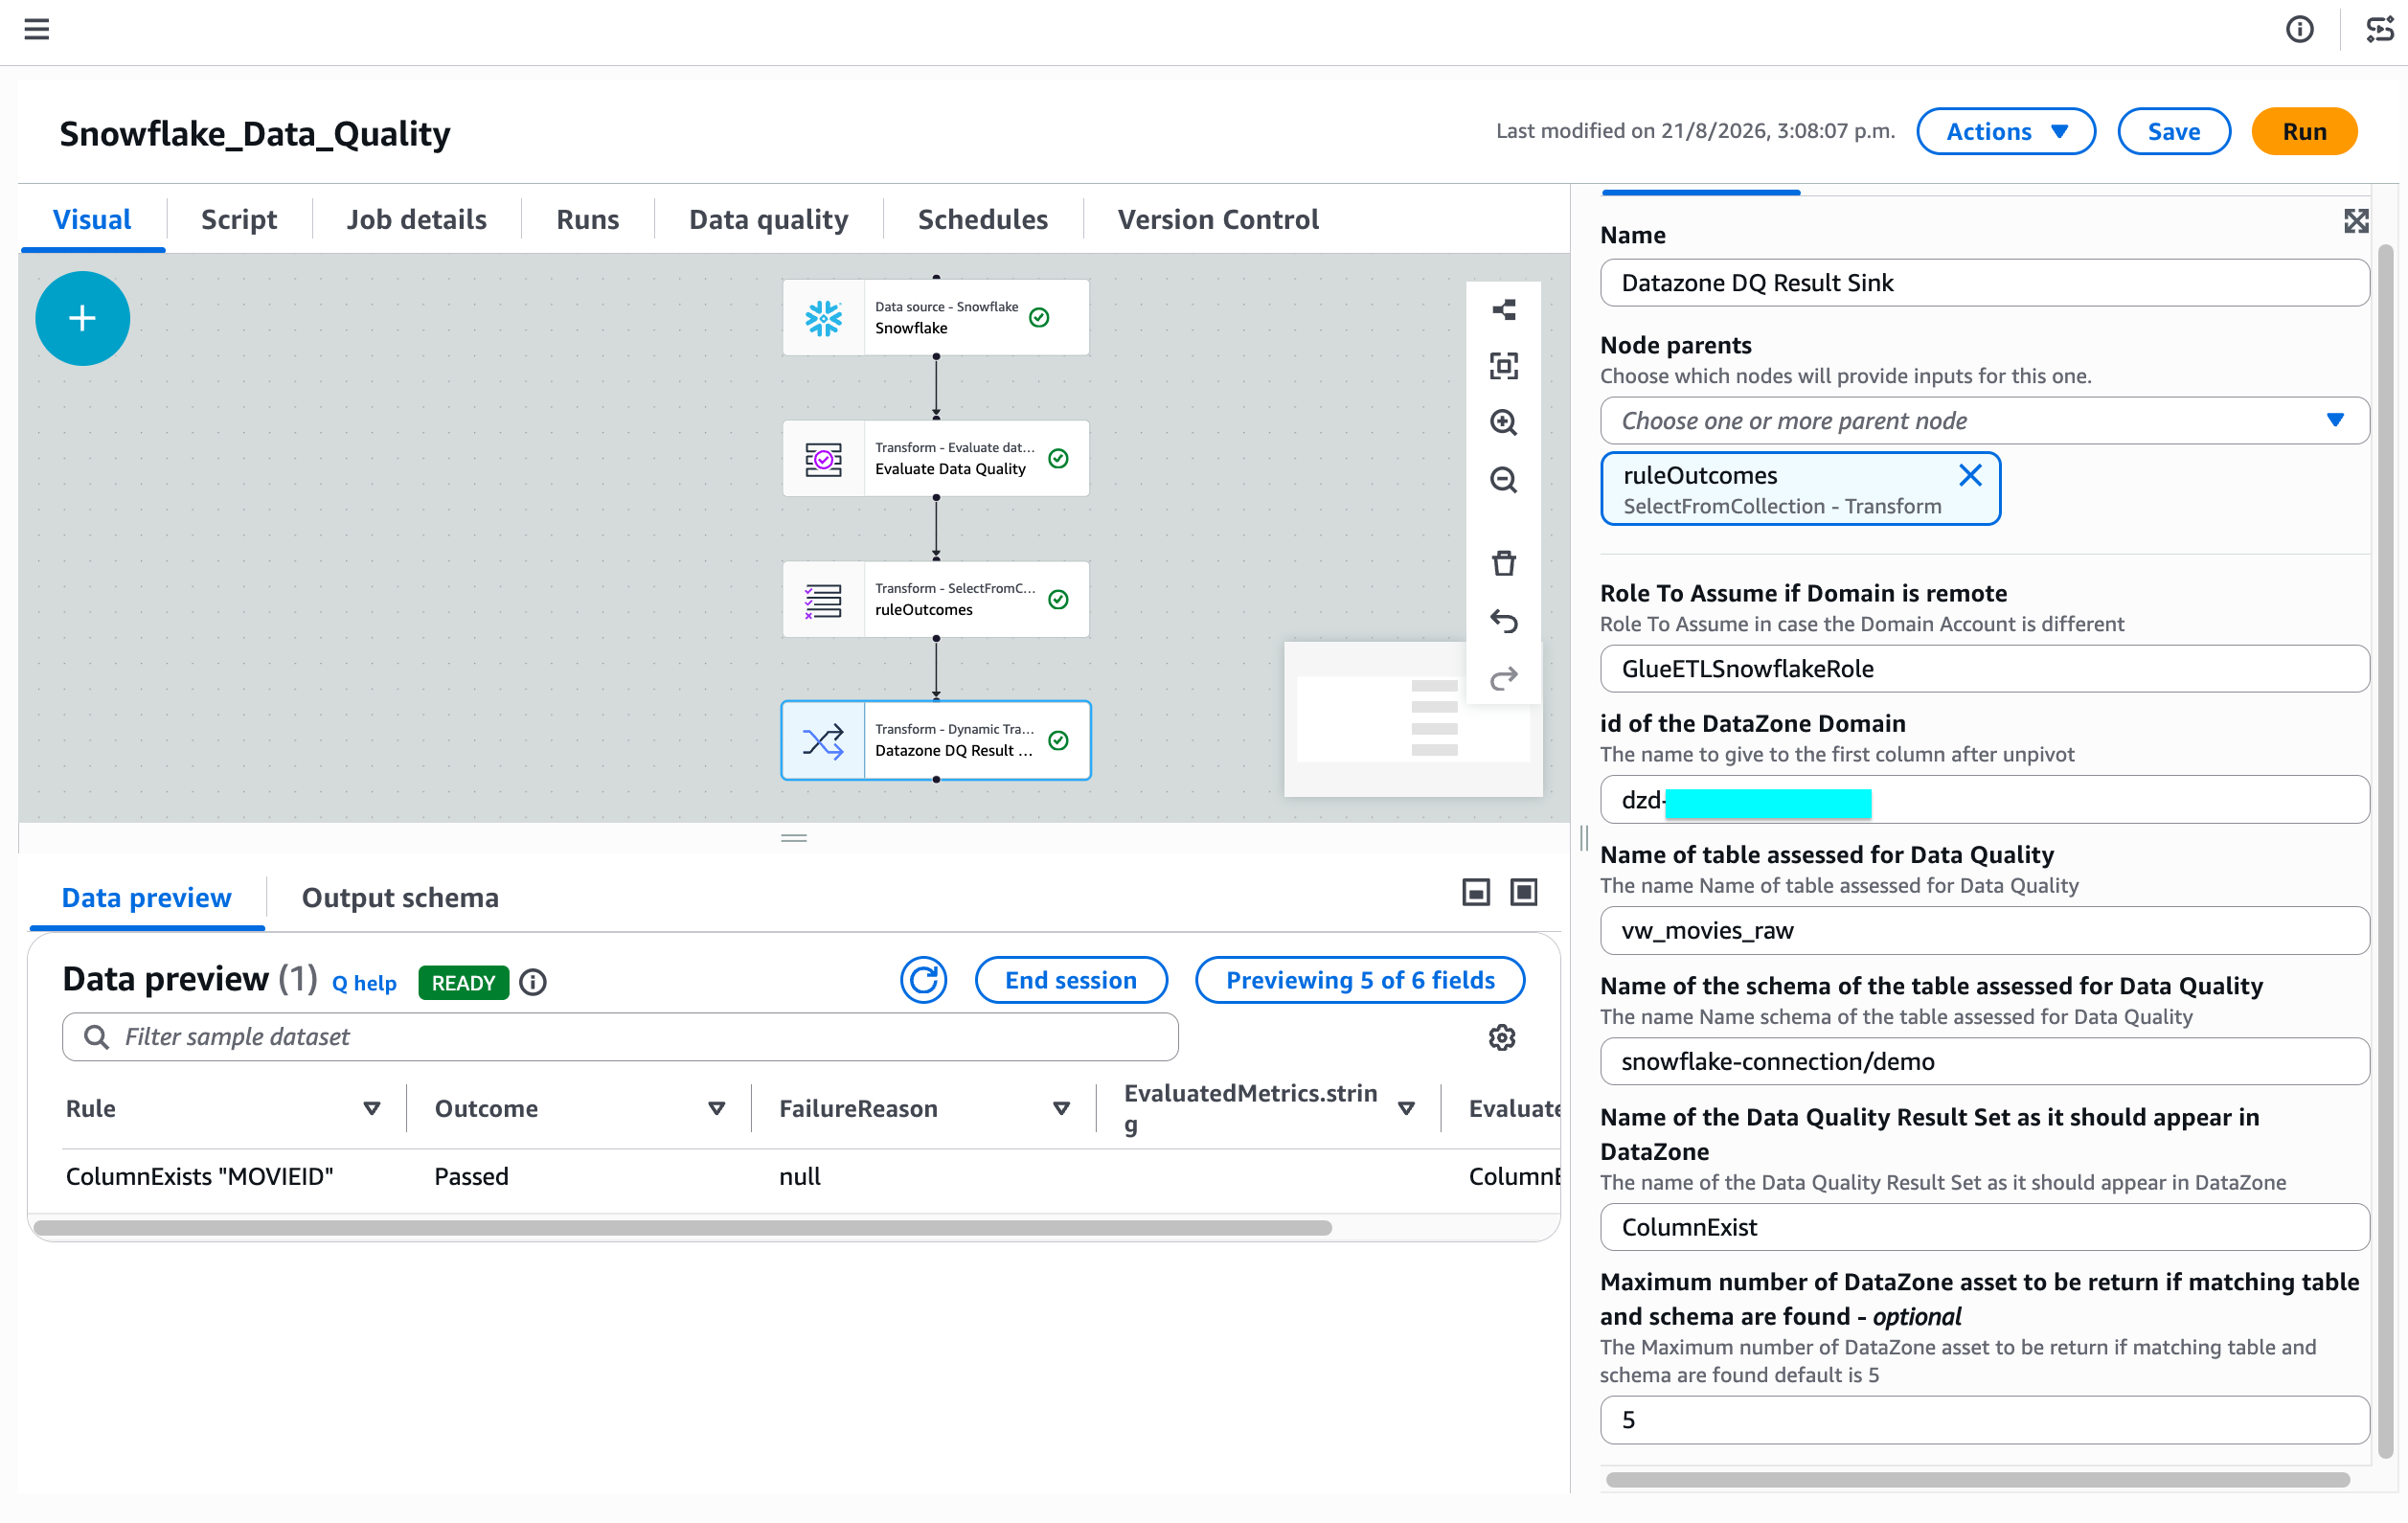
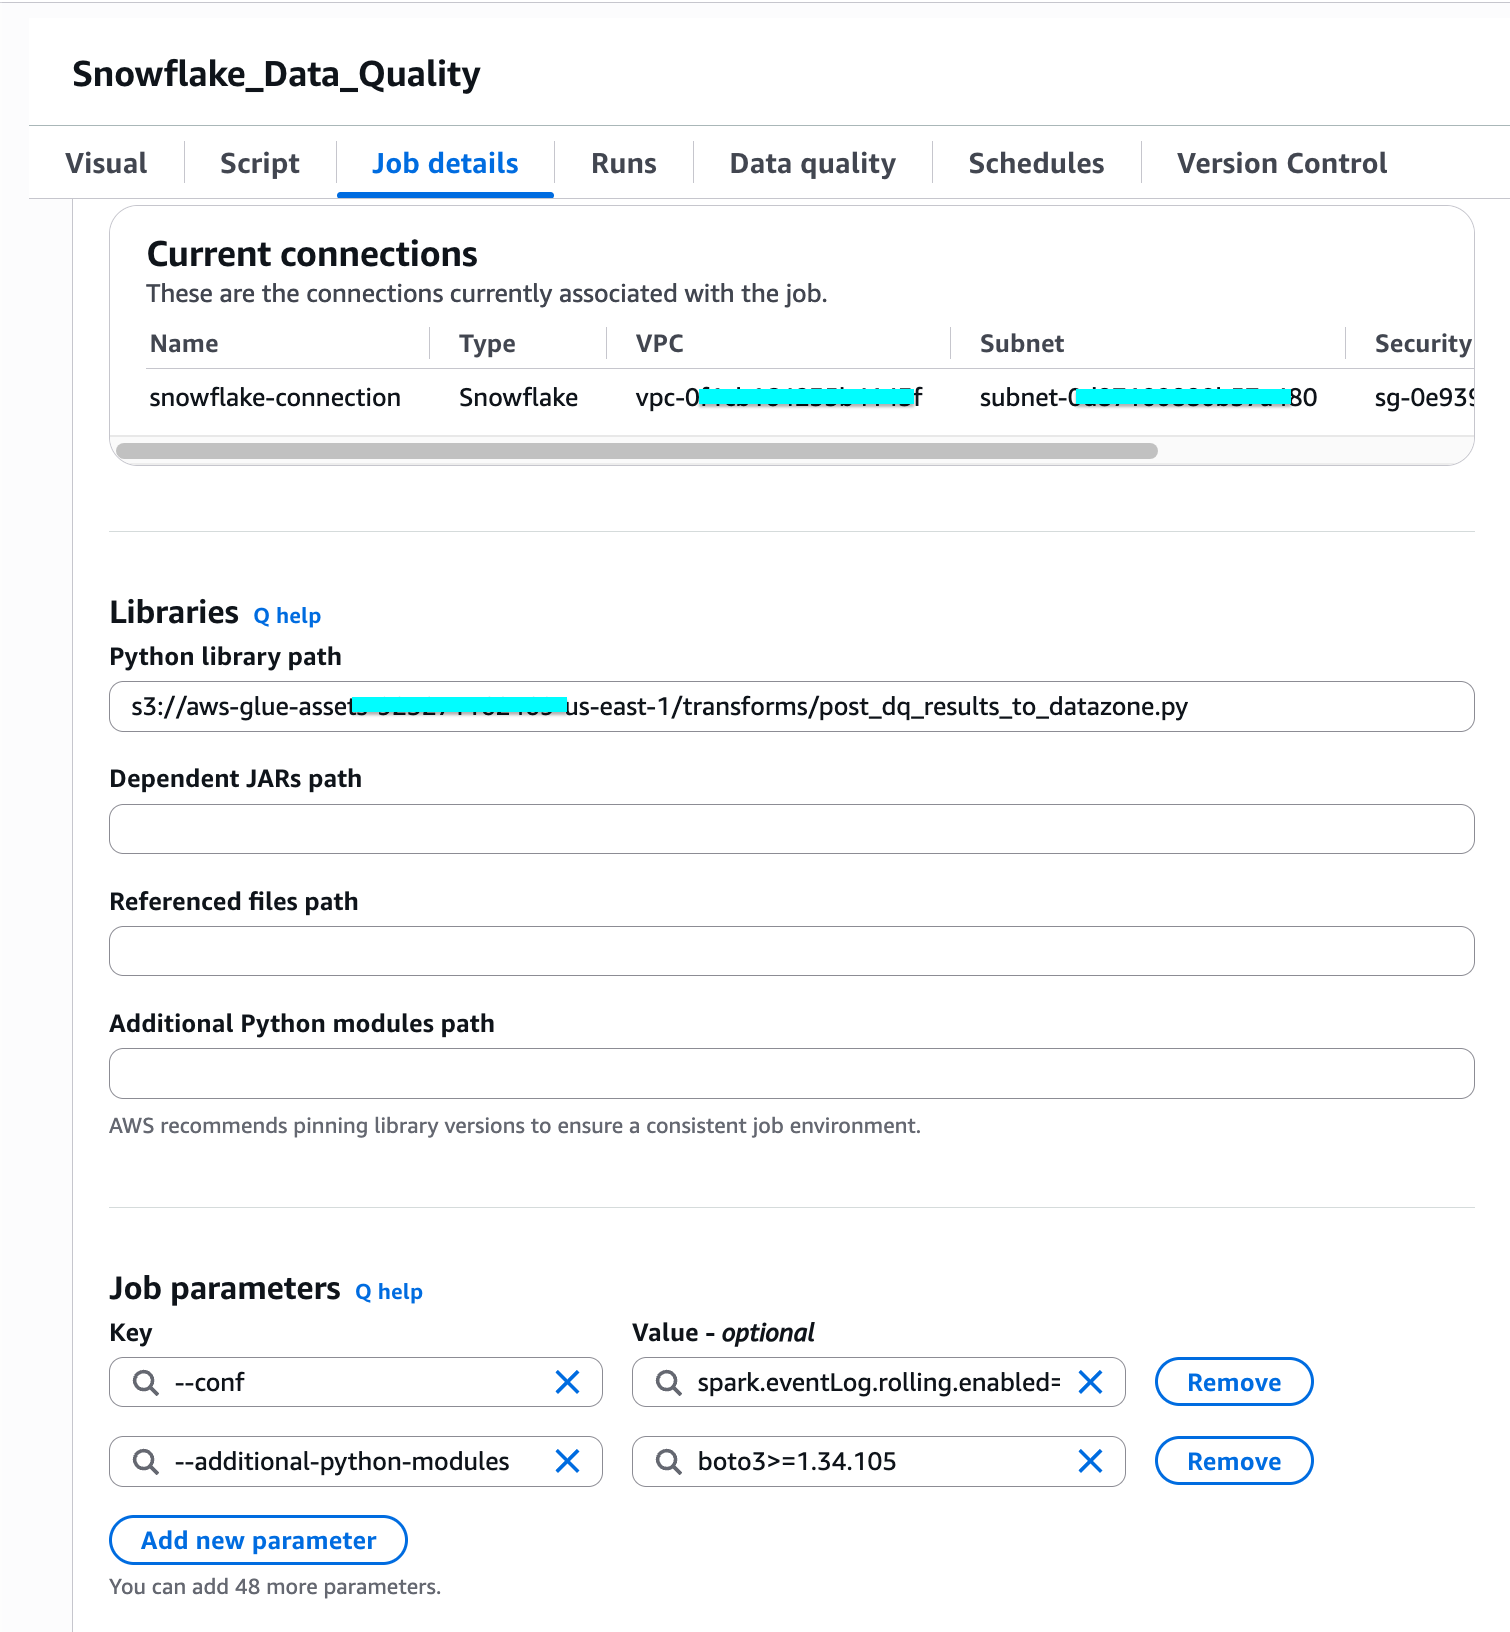
  4. Validate data quality — AWS Glue Data Quality runs validation rules against the federated Snowflake data and publishes the data quality results directly to the corresponding asset in Amazon SageMaker Catalog.
  5. Consume data — Users access Snowflake data through two paths:
    1. Publisher project users — Query data with SQL Analytics — Users in the publisher project can query the Snowflake data directly using Amazon SageMaker Unified Studio SQL Analytics for interactive exploration and analysis, without copying or moving data.
    2. Consumer project users — Discovery and subscription through SageMaker Catalog — Other Amazon SageMaker consumer projects discover the published asset in the Amazon SageMaker Catalog, subscribe to it, and consume the data for their analytics and machine learning workloads.

Prerequisites

To follow along, you need:

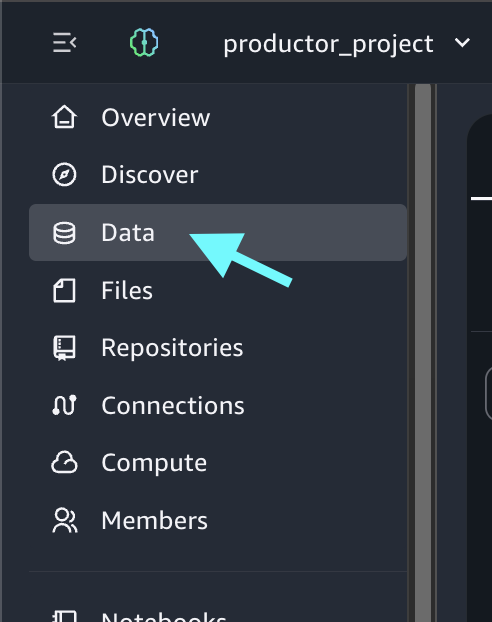
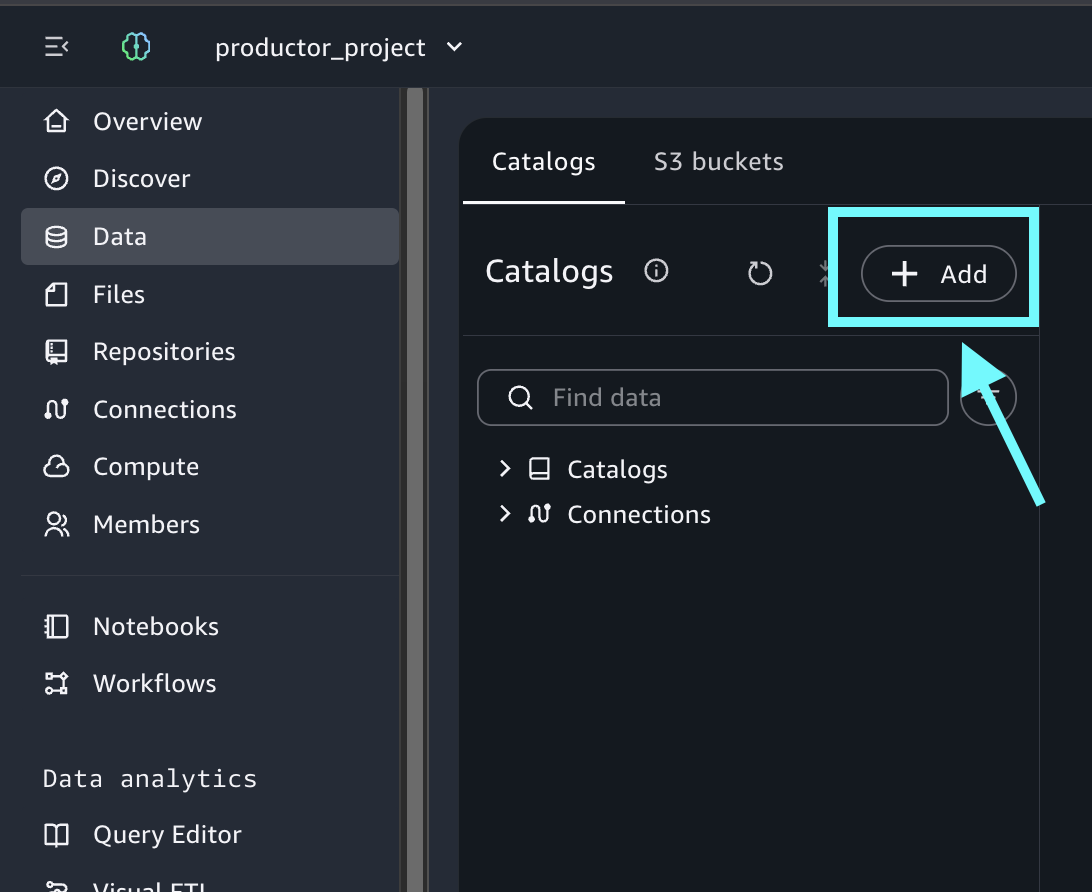
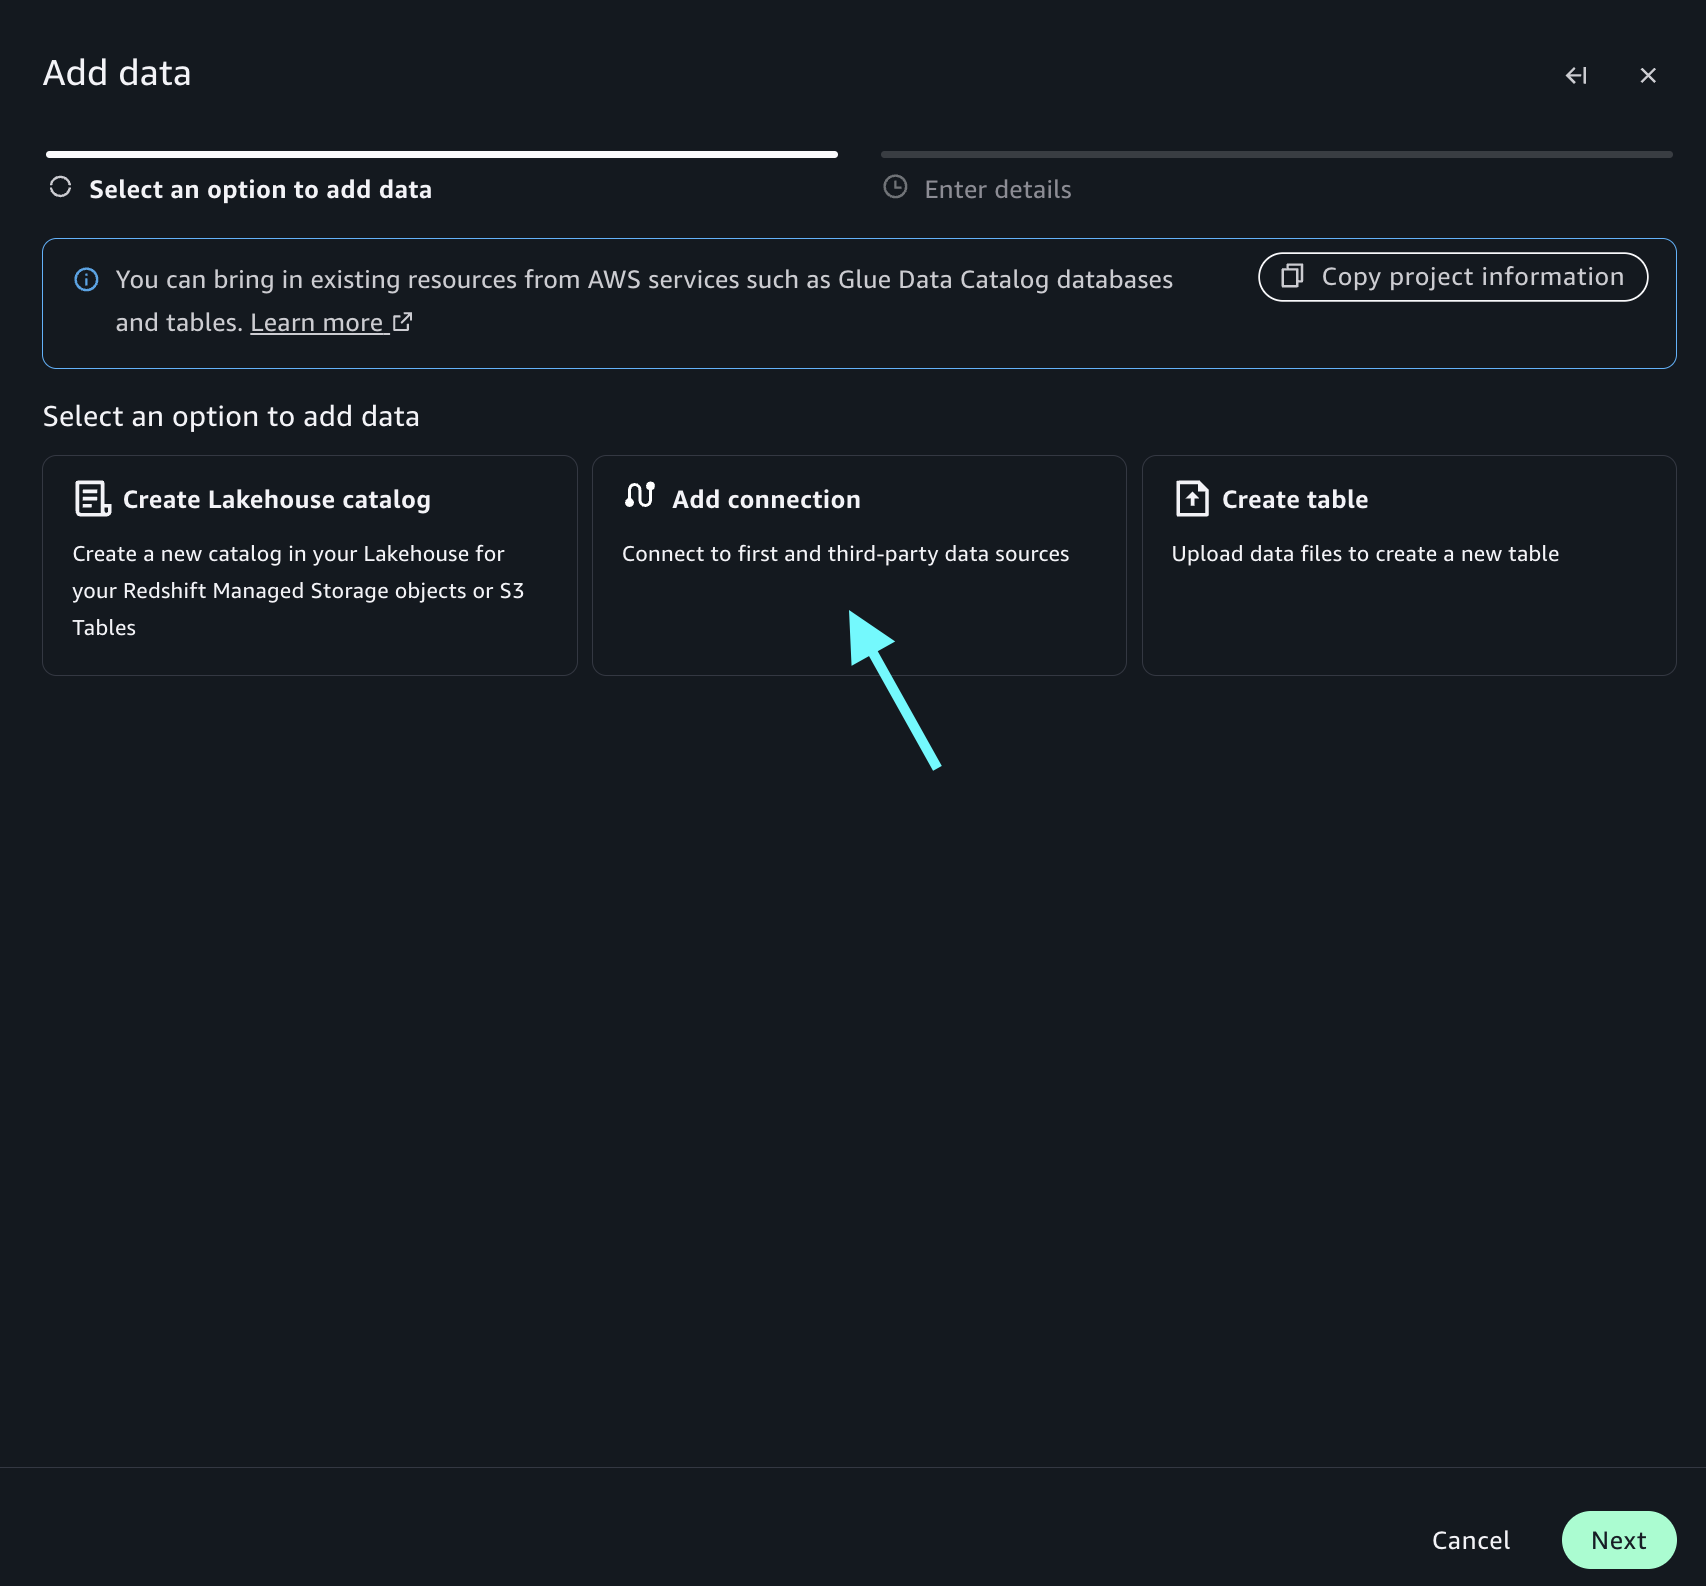
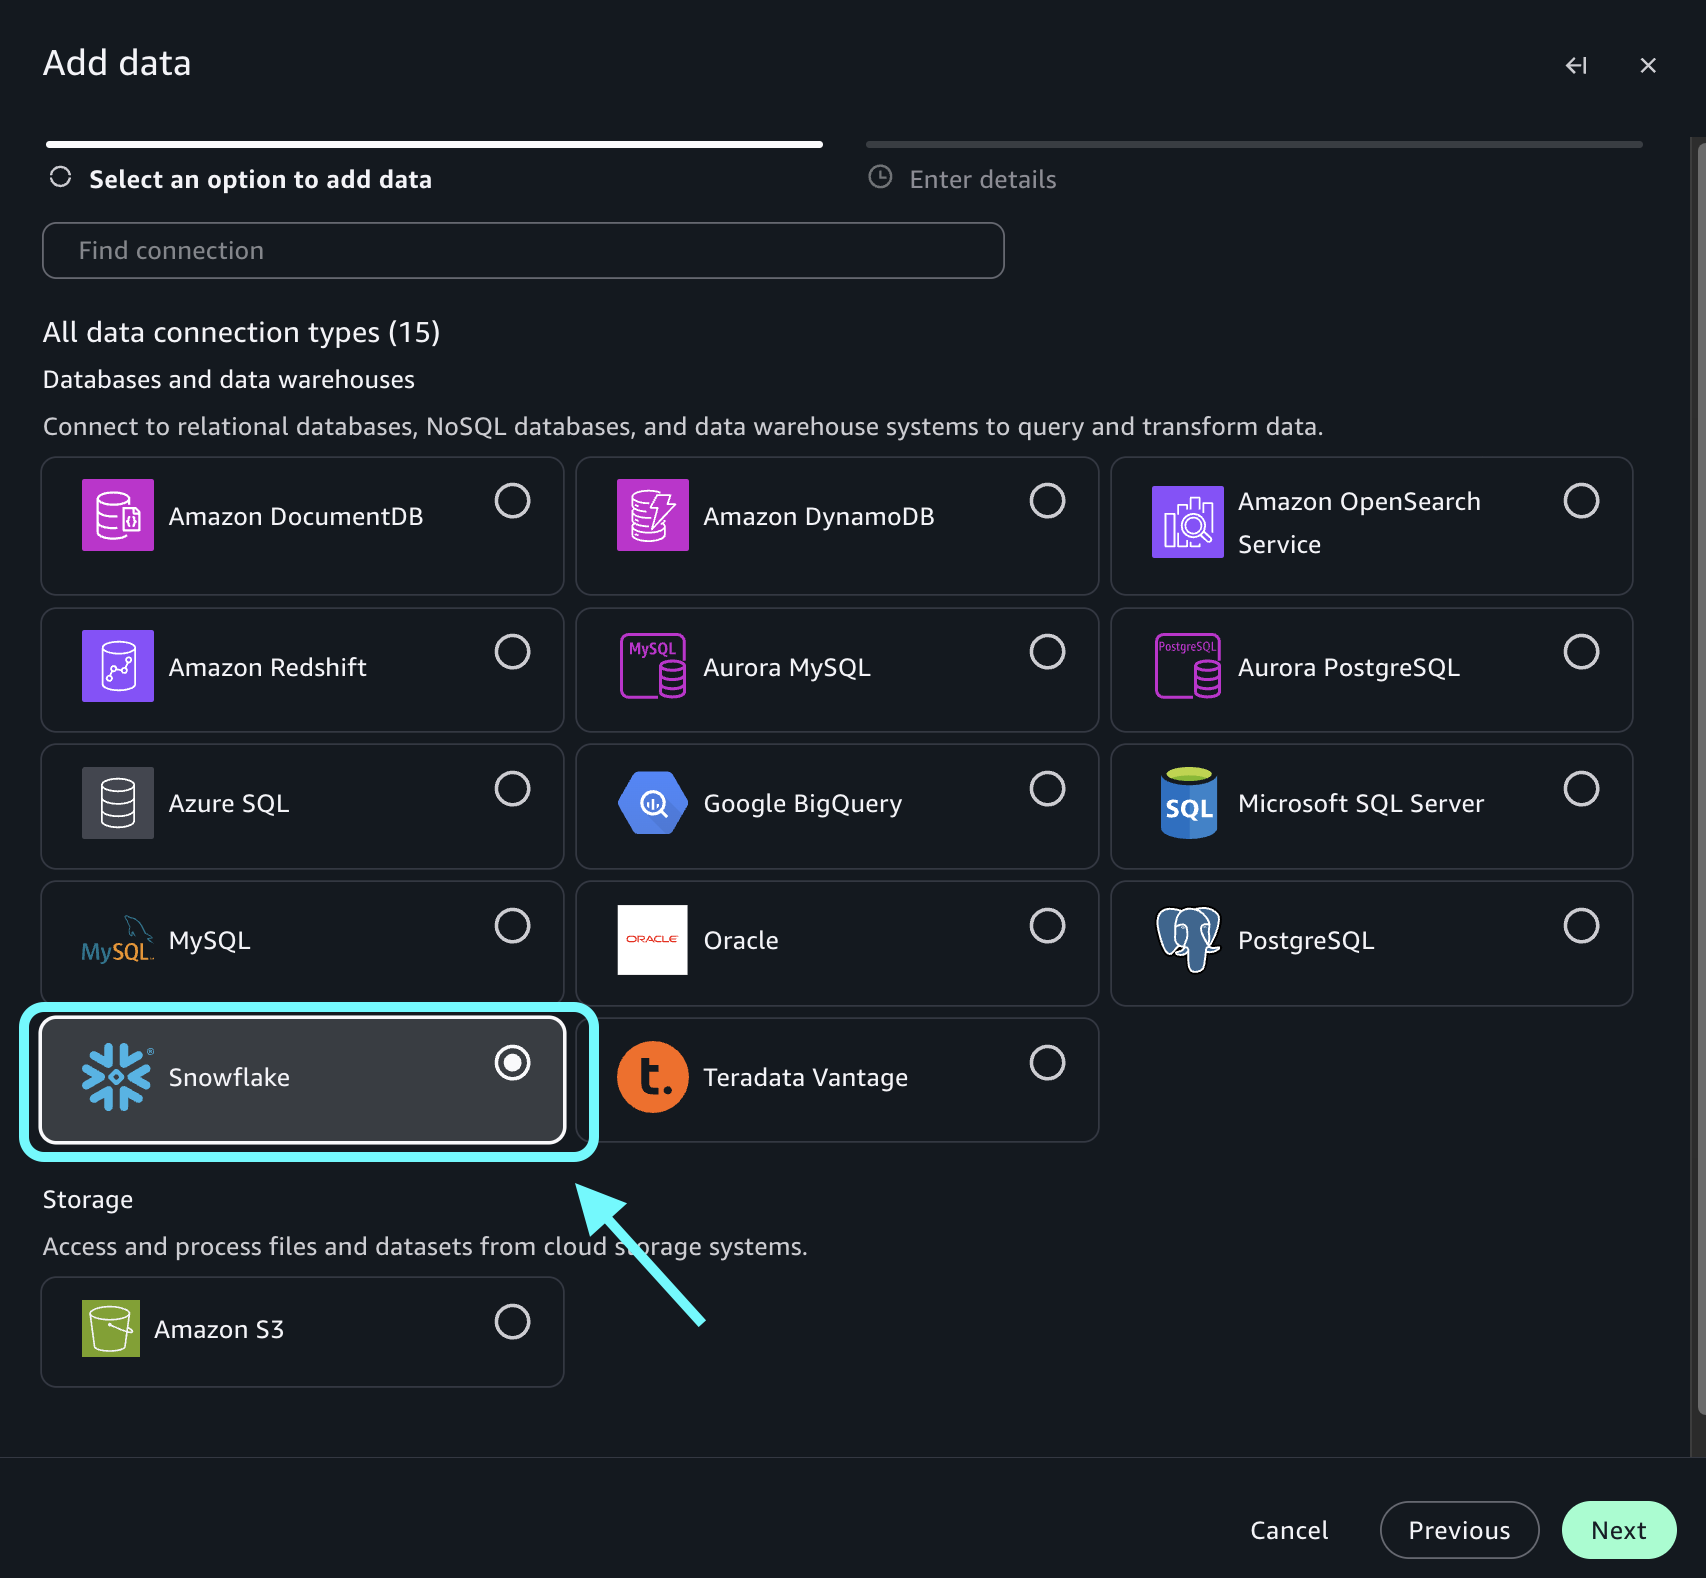
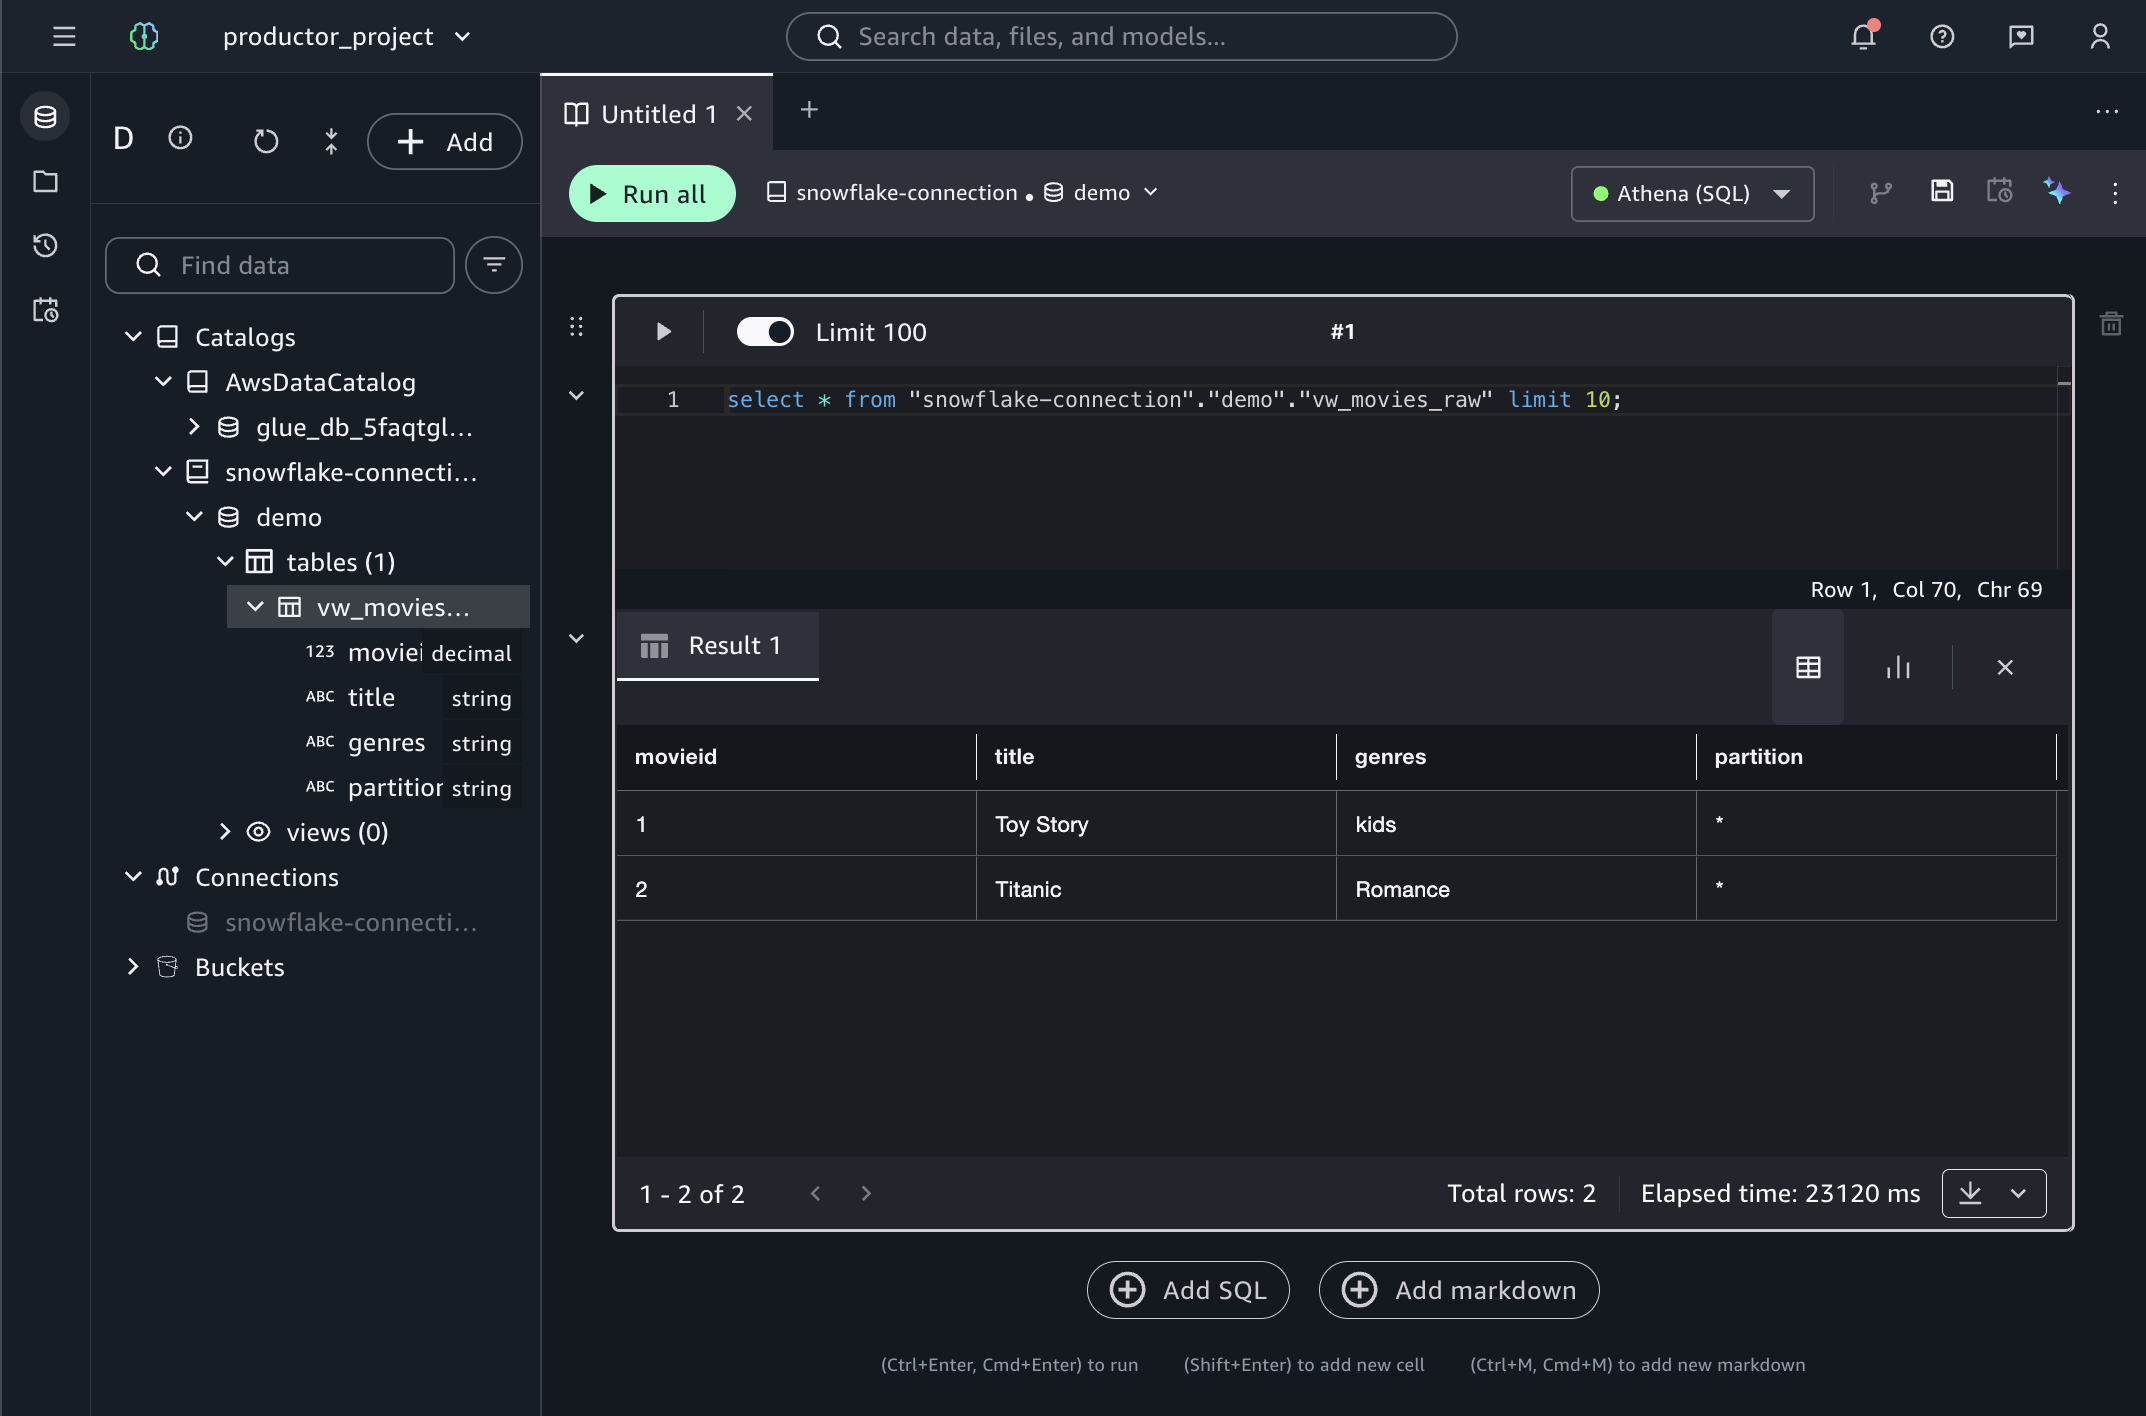
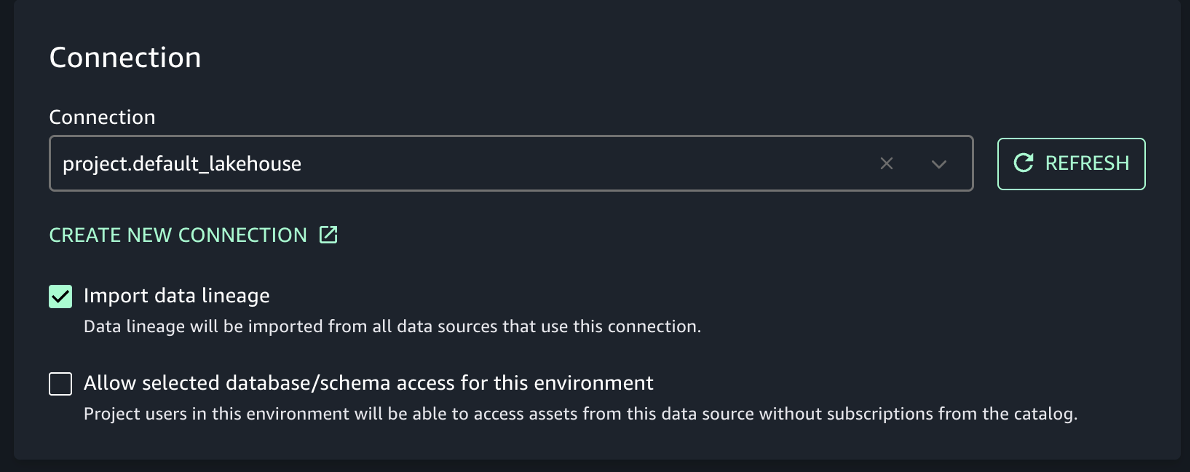
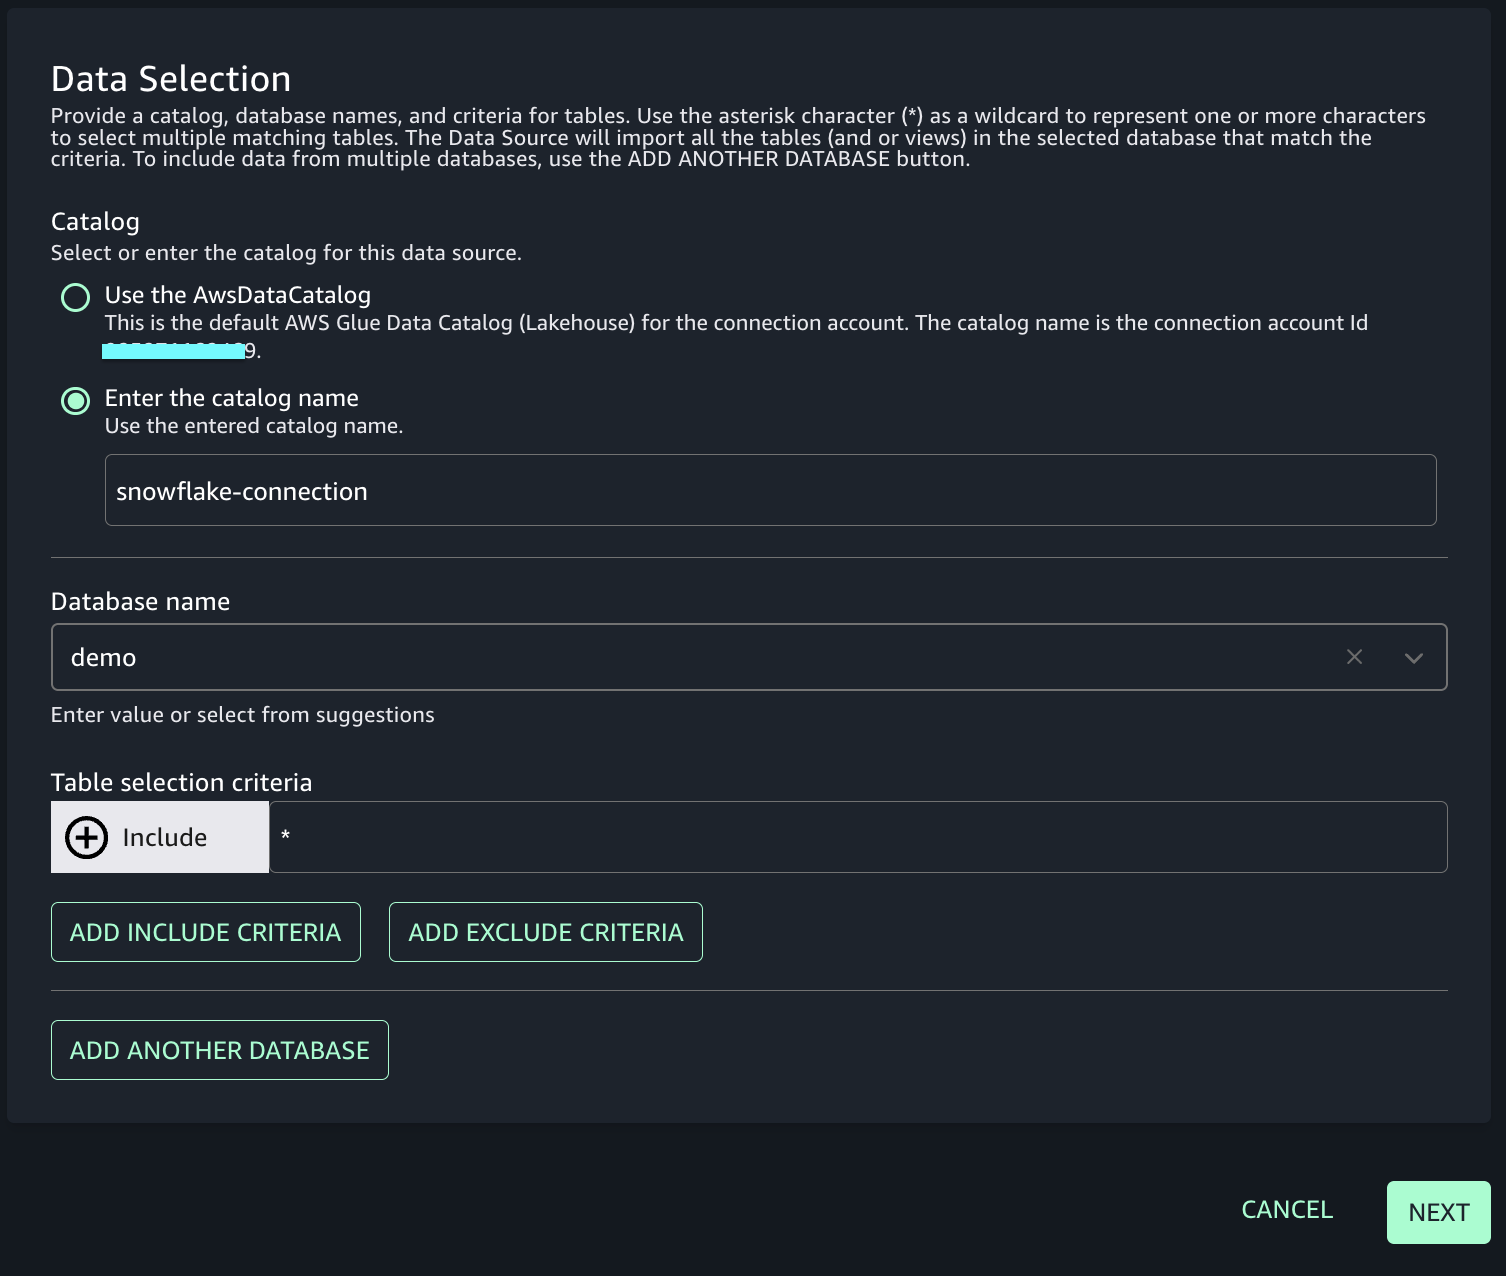
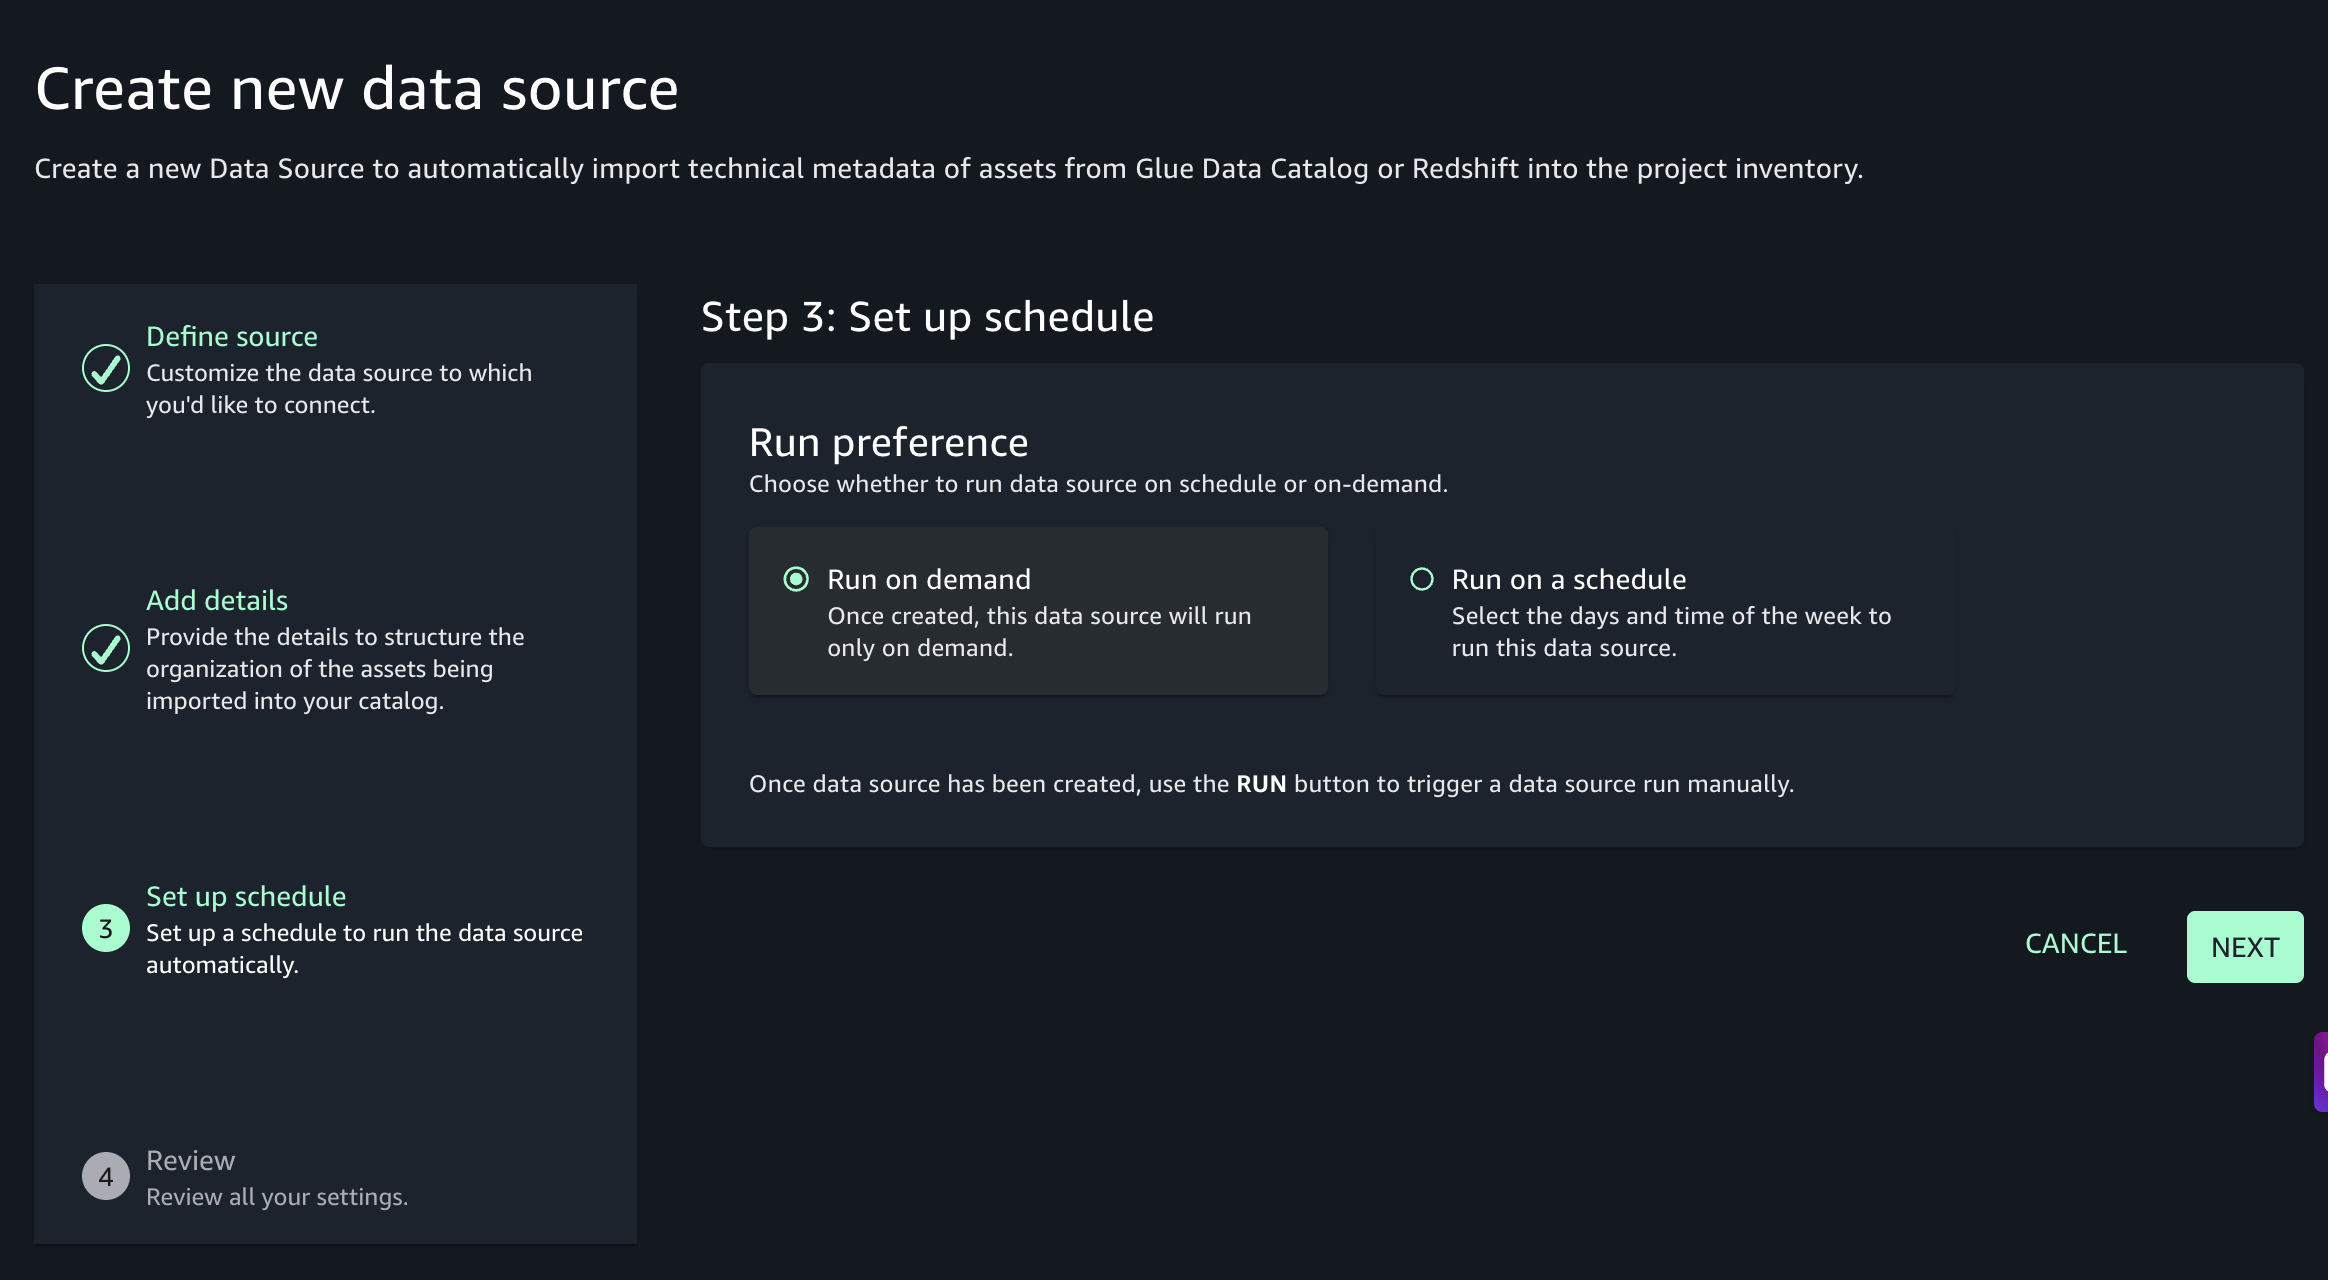
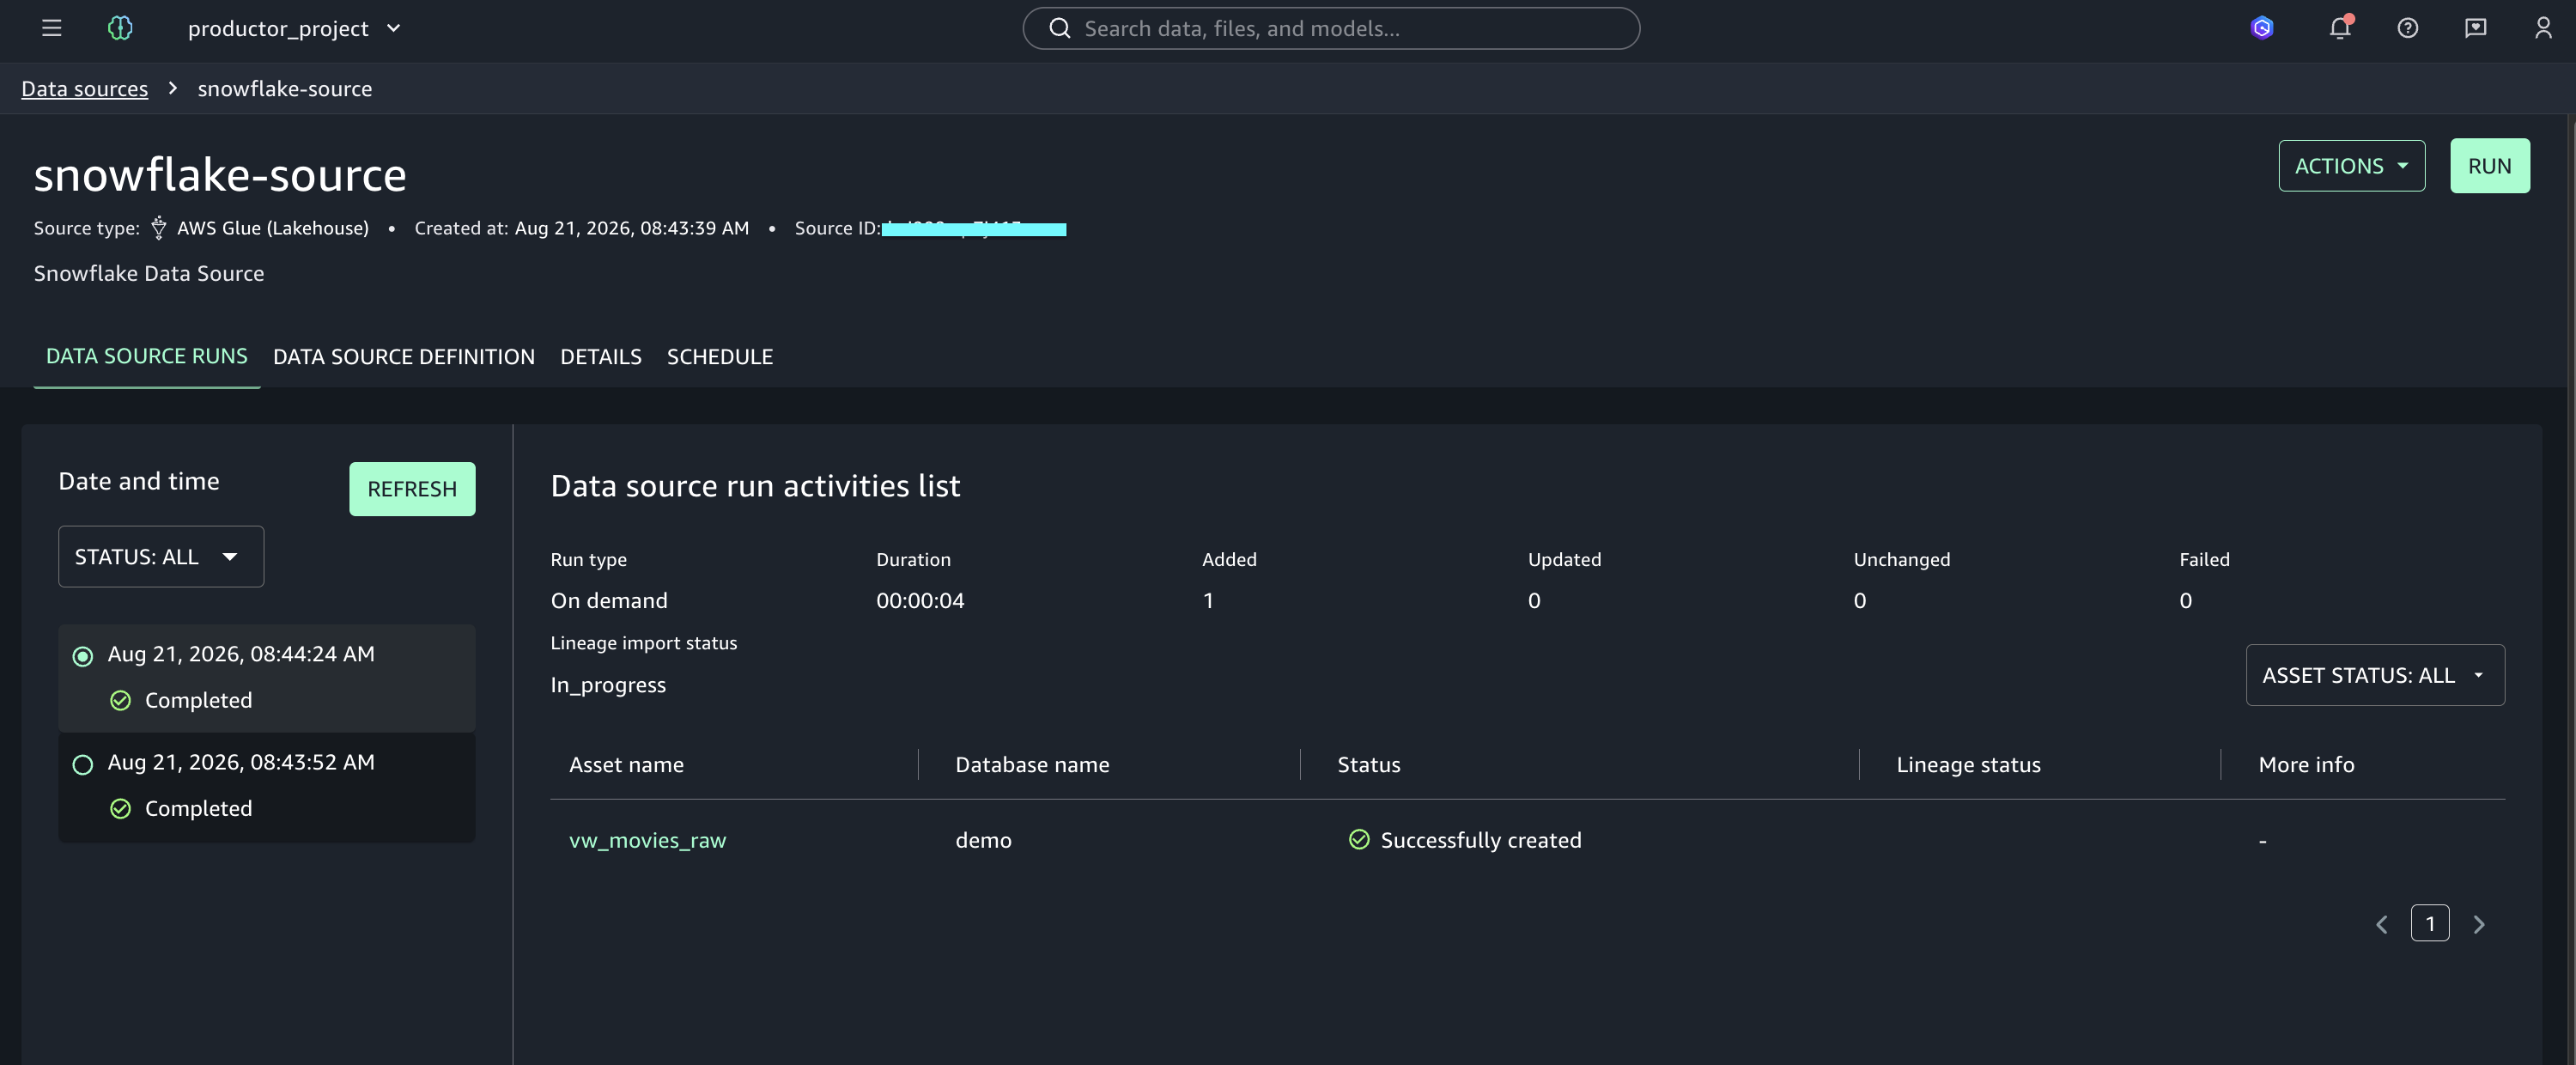
  • An active Snowflake account with administrator access.
  • Tables or views created within a schema inside a Snowflake database.
  • An Amazon SageMaker Unified Studio and project created.
  • An Amazon Simple Storage Service (Amazon S3) bucket for AWS Glue assets.
  • Appropriate AWS Identity and Access Management (IAM) permissions configured (Amazon SageMaker Catalog is built on Amazon DataZone, so the IAM actions use the datazone: prefix.)

Your AWS Glue job execution role requires specific permissions to interact with Amazon SageMaker Catalog.

Required IAM policies for the AWS Glue job role

1. Amazon SageMaker Catalog search and listing permissions: Attach a policy that allows the AWS Glue job to search and list assets in Amazon SageMaker Catalog.

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": [
        "datazone:SearchListings",
        "datazone:GetListing",
        "datazone:ListDomains",
        "datazone:GetDomain"
      ],
      "Resource": "arn:aws:datazone:<REGION>:<ACCOUNT_ID>:domain/<DOMAIN_ID>"
    }
  ]
}

2. Amazon SageMaker Catalog time series data posting permissions: Add permissions to post data quality metrics:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Effect": "Allow",
      "Action": [
        "datazone:PostTimeSeriesDataPoints",
        "datazone:GetAsset",
        "datazone:ListAssetRevisions"
      ],
      "Resource": "arn:aws:datazone:<REGION>:<ACCOUNT_ID>:domain/<DOMAIN_ID>"
    }
  ]
}

Configure the AWS Glue job role as an Amazon SageMaker domain user

Configure the IAM role used by your AWS Glue job as a domain user. In the Amazon SageMaker console, navigate to your domain, choose Access management, and add the AWS Glue job execution IAM role as a domain user.

Project-level permissions

Add the AWS Glue job execution role as a project member with Owner permissions. Navigate to your project, go to Project settings > Members, and add the role.

For more information about IAM roles for AWS Glue, see the AWS Glue security documentation. For Amazon SageMaker Unified Studio permissions, refer to the Amazon SageMaker Unified Studio administrator guide.

Querying Snowflake datasets from Amazon SageMaker Unified Studio

The following sections walk you through connecting Snowflake to Amazon SageMaker Unified Studio and running data quality validation with results displayed in Amazon SageMaker Catalog.

Identifying information in Snowflake

First, gather your Snowflake connection details. You need a Snowflake account with tables or views created at the schema level within a database.

To obtain Snowflake connection information:

  1. Navigate to your Snowflake environment and sign in with administrator credentials.

    Snowflake sign-in screen for administrator credentials
  2. Choose your user account and choose Connect a tool to Snowflake.

  3. Note the Account/Server URL displayed on the screen.
  4. Choose the Config File tab, select values for Warehouse, Database, and Schema, and copy these values for use in the next section.

Creating the connection in Amazon SageMaker Unified Studio

The Add Connection feature stores Snowflake connectivity details including credentials, server, and database information. Amazon SageMaker Unified Studio uses this connection to federate the Snowflake catalog through AWS Glue, so you can query data within minutes of setup.

You need an Amazon SageMaker Unified Studio domain and a project, which acts as a data producer project.

To create the Snowflake connection:

  1. In your Amazon SageMaker Unified Studio project, go to Overview.

    SageMaker Unified Studio project Overview page
  2. Choose Data.

    Data option in the SageMaker Unified Studio project navigation
  3. Choose + Add, then choose Add Connection.

    Add menu in SageMaker Unified Studio with the Add Connection option
    Add Connection panel in SageMaker Unified Studio
  4. Choose Next.
  5. Select Snowflake and choose Next.

    Connection type selection showing Snowflake in SageMaker Unified Studio
  6. Complete the connection details:
    • Name: snowflake-connection.
    • Description (Optional): Enter a description for your connection.
    • Host: Your Snowflake account URL (for example, XXXXXXXXX-XXX000000.snowflakecomputing.com).
    • Port: 443.
    • Database: Your database name (for example, sm_demo).
    • Warehouse: Your warehouse name (for example, COMPUTE_WH).
    • Schema: Your schema name (for example, demo).
    • Additional Properties:
      • Register in AWS Glue Data Catalog: Turn on checkbox.
      • Case conflict handling: Select the option based on Snowflake naming syntax.
    • Authentication:
      • Username: Your Snowflake username.
      • Password: Your Snowflake password.
    Snowflake connection details form with name, host, port, database, warehouse, and schema fields
    Connection form showing authentication and AWS Glue Data Catalog registration options
  7. Choose Add Data.

After creating the connection, wait a few minutes for the federated connection to be established. Search within Amazon SageMaker Unified Studio for the database and created objects.

Federated Snowflake database and objects appearing in SageMaker Unified Studio search

Federated Snowflake tables registered in the AWS Glue Data Catalog

With the Snowflake connection established and the federated tables registered in AWS Glue Catalog, you’re now ready to query Snowflake data directly from Amazon SageMaker Unified Studio, without moving or replicating any data.

Query results from a federated Snowflake table in the SageMaker Unified Studio query editor

How federated queries work

When you run a query in the Amazon SageMaker Unified Studio query editor against a federated Snowflake table, Amazon Athena runs the request. Athena is the underlying query engine integrated into Amazon SageMaker Unified Studio. Athena reads the table definition from AWS Glue Catalog, connects to Snowflake through the established connection, and pushes the query down for execution. Athena returns results directly to the query editor while Snowflake processes the data in place, and only the query results travel across the connection. Amazon SageMaker Unified Studio doesn’t copy data to S3 or any intermediate storage.

After you’ve validated that queries return the expected results, the next step is to publish this dataset to Amazon SageMaker Catalog, making it discoverable and shareable across your organization.

Publishing Snowflake datasets to the SageMaker Catalog

Now that your Snowflake connection is configured, you can publish your datasets to the Amazon SageMaker Catalog, making them discoverable and shareable across your organization.

Creating data assets in SageMaker Catalog

Data assets in Amazon SageMaker Catalog are the cataloged representation of your data resources. They help teams discover, govern, and share data across your organization.

In this section, you create a data asset associated with a Snowflake table. This process transforms a technical Snowflake table into a cataloged resource enriched with business metadata.

To create a data source:

  1. In your Amazon SageMaker Unified Studio project, go to Manage.

    Manage tab in the SageMaker Unified Studio project
  2. Choose Data Sources.
  3. Choose Create Data Source.

  4. Select the AWS Glue option.

    Data source type selection showing the AWS Glue option
  5. Turn on the Import data lineage checkbox and select the connection: project.default_lakehouse.

    Data source configuration with Import data lineage and the project.default_lakehouse connection selected
  6. Complete the form and choose Next:
    • Catalog: Select Enter the catalog name and enter snowflake-connection.
    • Database name: Enter your database name (for example, movies).
    • Table selection criteria: Enter * for all tables in the database, or enter a specific table name.
    Data source form showing catalog name, database name, and table selection criteria
  7. Keep the default options and choose Next until you reach the summary screen.

    SageMaker Unified Studio data source configuration summary screen
    Data source review screen before creation
  8. Review your settings and choose Create.

To extract metadata and publish assets:

  1. Choose Run to start extracting metadata from AWS Glue Data Catalog.

    Data source detail page with the Run option to extract metadata from the AWS Glue Data Catalog
  2. Wait for the run to complete.
  3. Go to Assets to view the Asset Inventory.

    Asset inventory in SageMaker Catalog after the data source run completes

The following screenshot shows the asset inventory after the data source run completes.

  1. Choose an asset to view its details.

    Asset detail page in SageMaker Catalog showing the Snowflake table metadata

At this point, you can enrich the business context by choosing Generate Descriptions. Amazon SageMaker Catalog analyzes the asset’s technical structure and generate:

  • Business descriptions in natural language for the asset.
  • Contextual definitions for each field/column.
  • Suggested glossary terms that could be applied.
  1. After your asset has been enriched with the necessary business metadata, you can publish it to the Amazon SageMaker Catalog by choosing Publish Asset.

Publish Asset option on the enriched Snowflake asset in SageMaker Catalog

The Snowflake enriched asset is now available to data consumers across your organization. Other users can discover it, subscribe to it, and consume it without data replication.

Implementing data quality rules with AWS Glue Data Quality

This section explains how to apply data quality validations to Snowflake data using AWS Glue Data Quality and visualize results in Amazon SageMaker Catalog.

Setting up the custom transform

Upload two files to an Amazon S3 bucket in the same AWS account where you run AWS Glue:

Copy both files to your AWS Glue assets S3 bucket in the transforms folder (s3://aws-glue-assets-<account-id>-<region>/transforms). AWS Glue Studio reads all JSON files from this folder to register custom visual transforms.

Custom transform files uploaded to the transforms folder in the AWS Glue assets S3 bucket

In the following sections, we walk you through the steps of building an ETL pipeline for data quality validation using AWS Glue Studio.

Creating the AWS Glue Visual ETL job

AWS Glue for Spark provides built-in support for reading from Snowflake data sources.

To create a new visual ETL job:

  1. Open the AWS Glue console at https://console.aws.amazon.com/glue/. Choose ETL jobs, then Visual ETL.

    AWS Glue console showing ETL jobs and the Visual ETL option

Establishing the Snowflake connection

To add a Snowflake source:

  1. In the job pane, choose Snowflake as your source. For Snowflake connection, select the connection that you created earlier. Specify the relevant schema and table for data quality checks.

    Snowflake source node configured in the AWS Glue visual ETL job

The visual editor displays the Data source properties panel where you select your connection, database, and enter a custom query targeting your Snowflake table.

Applying data quality rules

After establishing the Snowflake connection, configure the data quality evaluation step using the Data Quality Definition Language (DQDL).

To add data quality validation:

  1. Choose Transform and choose Evaluate Data Quality.
  2. Define domain-specific data quality rules using DQDL. For more information, see the AWS DQDL documentation.

    Evaluate Data Quality transform with DQDL rules in AWS Glue Studio
  3. Choose to output the data quality results. Optionally, store outcomes in Amazon S3 or publish to Amazon CloudWatch with alert notifications.

The preview of the data quality results from the ruleOutcomes node shows the outcomes of each rule.

Preview of the data quality rule outcomes from the ruleOutcomes node

Post the data quality results to Amazon SageMaker Catalog

To configure the custom transform:

  1. Add the Datazone DQ Result Sink transform to your job.
  2. Connect the ruleOutcomes node output to this transform.
  3. Complete the parameters:
    • Role to assume (Optional): Only needed for associated accounts.
    • Domain ID: Your Amazon SageMaker Unified Studio domain ID (found in the Amazon SageMaker Unified Studio portal).
    • Table name and Schema name: Same values used when creating the Snowflake source transform.
    • Data quality ruleset name: The name you want to give to the ruleset in Amazon SageMaker Catalog.
    • Max results: Maximum number of assets to return in case of multiple matches.

The following image shows the complete job graph with the Datazone DQ Result Sink transform configured.

AWS Glue visual ETL job graph with Snowflake source, Evaluate Data Quality, ruleOutcomes, and Datazone DQ Result Sink nodes

The visual editor displays four nodes connected sequentially: the Snowflake data source, the Evaluate Data Quality transform, the ruleOutcomes SelectFromCollection transform, and the Datazone DQ Result Sink transform.

To configure job parameters:

  1. Choose Job details.
  2. In Job parameters, add the following key-value pair:
    • --additional-python-modules
    • boto3>=1.34.105
  3. Save and run the job.

AWS Glue job parameters with the additional-python-modules key set to boto3

Visualizing data quality results in the SageMaker Catalog

After the AWS Glue ETL job completes, you can view the data quality information directly in Amazon SageMaker Catalog. This is the key outcome of running data quality on a federated source: the asset gains quality scores and metadata without ever leaving Snowflake. This makes it trustworthy and ready for other teams across your organization to use. Data consumers can now discover this asset in Amazon SageMaker Catalog and evaluate its quality before subscribing, without needing direct access to Snowflake or running their own validation.

To view data quality results:

  1. Open the Amazon SageMaker Unified Studio console.
  2. Navigate to your project.
  3. Go to Assets.
  4. Choose the Snowflake data asset.
  5. View the data quality information displayed on the asset page.

The following image shows the asset page in Amazon SageMaker Catalog with the data quality score populated.

SageMaker Catalog asset page showing a populated data quality score for the Snowflake asset

Data Quality tab in SageMaker Catalog showing an overall score of 100 with the movies rule set passed

The Data Quality tab shows an overall score of 100 and lists the rule set movies with a Passed result (1/1). This confirms that the data quality checks from AWS Glue posted successfully to Amazon SageMaker Catalog.

Clean up

To avoid ongoing charges, remove the resources you created during this walkthrough:

  1. Delete the AWS Glue ETL job — Open the AWS Glue console, choose ETL jobs, select your job, and then choose Delete.
  2. Remove the AWS Glue connection — In the AWS Glue console, go to Connections, select the Snowflake connection, and then choose Delete.
  3. Delete the data source in SageMaker Catalog — In your Amazon SageMaker Unified Studio project, go to Data Sources, select the data source you created, and then choose Delete.
  4. Remove S3 assets — Delete the custom transform files from your s3://aws-glue-assets-<account-id>-<region>/transforms/ bucket.
  5. Remove IAM policies — Detach and delete the IAM policies you attached to the AWS Glue job execution role. Remove the role as a domain user and project member.

Conclusion

In this post, we showed you how to connect Snowflake to Amazon SageMaker Unified Studio for centralized data cataloging and quality validation. This approach maintains consistent governance without replicating data. Key benefits include:

  • Query without data movement: Access Snowflake data directly from Amazon SageMaker Unified Studio through federated queries, using the interoperable data architecture of AWS and eliminating time-consuming data replication.
  • Centralized governance: Maintain a single source of truth for data discovery, quality metrics, and governance policies across your distributed data estate.
  • Automated quality validation: Apply consistent data quality rules using AWS Glue Data Quality and visualize results directly in Amazon SageMaker Catalog.
  • Unified collaboration: Support data discovery and sharing across your organization through the publishing capabilities of Amazon SageMaker Catalog.

To get started, open the Amazon SageMaker Unified Studio console. To learn more about related topics, see Cross-account lakehouse governance with Amazon S3 Tables and SageMaker Catalog and Get started with AWS Glue Data Quality dynamic rules for ETL pipelines.


About the authors

Marco Duarte López

Marco Duarte López

Marco is a Data Specialist Solutions Architect at AWS, based in Santiago, Chile. He works with organizations across the region to design modern data architectures and governance frameworks that enable trusted, scalable data consumption. He is a member of the AWS Technical Field Community (TFC) for Analytics, where he specializes in Data & AI Governance, and has led data transformation programs for some of the largest enterprises in the region.

Diego Ortiz

Diego Ortiz

Diego is a Senior Data Strategy Solutions Architect for Latin America based in San Juan, Puerto Rico, with 14+ years of experience in technology roles. He supports organizations across countries and industries to develop data and AI strategies aligned with their business objectives, combining strategic vision with deep technical expertise in data and AI technologies. He is a core member of the Data Governance global community at AWS and leads the analytics technical community in the Spanish-speaking countries of Latin America.

Operationalizing least privilege: Automate IAM remediation through your CI/CD pipeline

Post Syndicated from Luis Pastor original https://aws.amazon.com/blogs/security/operationalizing-least-privilege-automate-iam-remediation-through-your-ci-cd-pipeline/

The principle of least privilege is straightforward to articulate but challenging to maintain at scale. When teams first deploy applications to AWS, they often grant broader permissions than strictly necessary; it’s faster to get things working, and the plan is always to tighten permissions later. But later rarely comes. Permissions accumulate, AWS Identity and Access Management (IAM) principals that once needed broad access for initial deployment retain those permissions long after they’re necessary, and some principals stop being used entirely. Even small teams face this challenge—permission reviews aren’t a one-time task but an ongoing operational burden that demands automation.

AWS IAM Access Analyzer addresses detection and recommendation. It identifies unused permissions across IAM roles and users: actions that haven’t been exercised, services that haven’t been accessed, and principals that aren’t being assumed at all. For each finding, it generates a recommended policy with the excess permissions removed. Security teams can see exactly what to fix, but manual remediation doesn’t persist. A security engineer can right-size a role today, but if that role is defined in an AWS CloudFormation template or AWS Cloud Development Kit (AWS CDK) stack, the next deployment restores the original permissions. The fix must live where the role is defined, and not every role starts in the same place. Some are managed through infrastructure-as-code (IaC), where remediation means updating source code and deploying through a pipeline. Others were created manually through the AWS Management Console and have no code representation. And some principals aren’t being used at all and need a controlled decommission path. Each scenario requires a different remediation strategy.

This post walks through an automated remediation workflow that bridges the gap between detection and action. Instead of findings accumulating in a dashboard waiting for someone to investigate, the automation classifies each role by how it was created and produces a ready-to-review remediation artifact: a pull request with production-ready CDK code and a plain-English explanation for IaC-managed roles, an issue with the recommended policy and step-by-step IaC migration guidance for manually created roles, or a soft-disable issue with a monitored decommission plan for unused principals. Each output flows through your existing code review and issue tracking processes—the same workflows your teams already follow. By the end of this post, you’ll have a pattern that converts IAM Access Analyzer findings into tested, deployable code changes rather than a growing backlog of security tickets.

Understanding the problem

Unused IAM permissions increase the attack surface. Removing unused permissions limits the actions available to any compromised credentials, reducing potential impact. Roles that aren’t being assumed represent unused resources; removing them simplifies your IAM inventory and reduces potential access paths that aren’t actively monitored.

The challenge isn’t knowing what to fix. As we said earlier, Access Analyzer provides both the findings and the recommended policies. The challenge is acting on that knowledge consistently across your environment. Each finding requires context:

  • What the role does
  • Who created the role
  • Determining if the permission is unused or used infrequently
  • If the role is managed in a CloudFormation stack, or was created through the console

Multiply this by hundreds of roles and security teams face a backlog that grows faster than they can address it.

Manual remediation compounds the problem. A security engineer can right-size a role directly in the console, but that fix is fragile. If the role is defined in an IaC template, the next deployment restores the original permissions. If it was created manually, there’s no record of what changed or why, and no easy way to revert if the change causes issues.

This is where IaC changes the equation. When roles are defined in code, remediation means updating that code. Changes flow through pull requests, are reviewed by the team that owns the role, and deploy consistently across environments. The fix becomes permanent, not a point-in-time correction that drifts back on the next deployment. And because every change is tracked in version control, teams can confidently remove permissions knowing they can revert if something breaks. That safety net matters; it’s often the difference between a team acting on a finding and leaving it in the backlog.

Solution overview

The solution automates remediation by connecting four capabilities: IAM Access Analyzer for detection and policy recommendations, CloudTrail for role attribution, Amazon Bedrock for CDK code generation and plain-English explanations, and your existing continuous integration and delivery (CI/CD) pipeline for remediation execution. The workflow operates on a core principle: every IAM role has an origin, and that origin determines the remediation path.

Figure 1 shows the solution architecture: Amazon EventBridge triggers an AWS Lambda orchestrator on a daily schedule. The Lambda orchestrator integrates with IAM Access Analyzer, CloudTrail, Amazon Bedrock, and Amazon CloudWatch. Each finding is routed to one of three remediation paths: a pull request for IaC-managed roles, an issue for manually created roles, and a soft-disable issue for unused roles.

Figure 1: The daily remediation workflow; from scheduled trigger to the three role-based remediation paths

Figure 1: The daily remediation workflow; from scheduled trigger to the three role-based remediation paths

On each scheduled run, the automation retrieves active findings from IAM Access Analyzer and queries CloudTrail to determine how each role was created. Roles created through CloudFormation or AWS CDK have a traceable origin: the service principal, stack name, and originating repository. Roles created manually through the console have a different origin: the IAM user who created them and the timestamp. This distinction drives the remediation strategy.

For IaC-managed roles, the automation retrieves the IAM Access Analyzer-recommended policy and uses Amazon Bedrock to wrap it in production-ready CDK code that includes the role definition and policy statements and imports what your CI/CD pipeline needs to deploy the update. It then creates a pull request in the originating repository. The pull request (PR) includes the updated CDK code, a policy diff showing exactly which permissions are being removed, and a plain-English explanation of the changes, for example, “This change removes write access to S3, keeping only read and list permissions.” Your existing code review process evaluates the change, and after being merged, the fix deploys consistently across environments.

For manually created roles, the automation creates an issue that includes the IAM Access Analyzer-recommended policy with unused permissions removed, a diff highlighting the changes, and an Amazon Bedrock-generated explanation of what the permission changes accomplish. The issue also provides guidance on importing the role into your IaC codebase. This gives teams an immediate remediation path while encouraging long-term governance through IaC adoption.

For roles that aren’t being assumed at all, the automation takes a more cautious approach. Instead of taking direct action, it creates an issue recommending a soft-disable workflow: attach a deny-all policy to the role, monitor for 30 days to confirm no workload depends on it, then delete. The issue provides the steps and context, the team executes the decommission through their preferred process, whether that’s a console change, an AWS Command Line Interface (AWS CLI) script, or a PR removing the role from the IaC. This controlled decommission path reduces the risk of removing a role that’s used infrequently or seasonally.

The solution supports both single-account and organization-wide deployment. In single-account mode, it uses an ACCOUNT_UNUSED_ACCESS analyzer to process findings for one account. In organization mode, it uses an ORGANIZATION_UNUSED_ACCESS analyzer deployed in a delegated administrator account, which generates findings across all member accounts from a single vantage point. The Lambda function automatically detects which analyzer type is available and extracts the account ID from each finding’s resource Amazon Resource Name (ARN), so role attribution and remediation routing work the same way regardless of scope.

This three-path strategy acknowledges operational reality. Not all roles start in IaC, not all unused roles are safe to delete immediately, and forcing immediate migration isn’t always practical. The solution provides a clear path forward for each scenario: remediate IaC roles through code, give teams actionable recommendations for manually created roles, and safely decommission what’s no longer needed. Over time, your infrastructure becomes increasingly code-driven, and remediation becomes a routine part of your CI/CD process rather than a manual security task.

Technical details

Consider a company—call them AnyCompany—running 200 IAM roles across three AWS accounts. Some roles were created through AWS CDK stacks during initial deployment. Others were created manually through the console by engineers who needed quick access during incident response or prototyping. A handful haven’t been assumed in over 6 months. AnyCompany’s security team wants to act on their IAM Access Analyzer findings, but each role requires different handling. The solution’s architecture addresses this by routing each finding through a classification and remediation pipeline.

Figure 2 shows how each IAM Access Analyzer finding is processed:

  1. The finding is first checked against exclusions and excluded findings are skipped.
  2. Remaining findings are split by type: UnusedPermission findings retrieve a recommended policy from IAM Access Analyzer and then query CloudTrail for role origin, while UnusedIAMRole findings follow the unused role path.
  3. By origin, IaC-managed roles generate AWS CDK code using Amazon Bedrock and create a pull request.
  4. Manually created or unknown-origin roles create an issue with the recommended policy and IaC migration guidance.
  5. Unused roles create a soft-disable issue to deny-all, monitor for 30 days, then delete.
  6. All paths publish CloudWatch metrics.
Figure 2: Detailed component interactions—the orchestrator’s five steps, its four service integrations, and the three remediation paths

Figure 2: Detailed component interactions—the orchestrator’s five steps, its four service integrations, and the three remediation paths

The rest of this section walks through each component using AnyCompany’s roles as examples.

Exclusion filtering

Before processing any finding, the Lambda function loads an exclusion configuration and checks whether the role should be skipped. This prevents the automation from creating remediation items for roles that legitimately need broad permissions.

{
  "excluded_roles": [
    "arn:aws:iam::123456789012:role/BreakGlassRole",
    "arn:aws:iam::123456789012:role/ServiceLinkedRole"
  ],
  "excluded_permissions": [
    "iam:*",
    "sts:AssumeRole"
  ],
  "excluded_by_tag": {
    "NoRemediation": ["true"],
    "CriticalService": ["true"]
  },
  "min_unused_days": 30
}

AnyCompany excludes their break-glass role (used only during incidents), any service-linked roles, and roles tagged CriticalService. The min_unused_days threshold prevents false positives from seasonal workloads; a role that ran a quarterly batch job 25 days ago won’t generate a finding.

Detection and analysis

IAM Access Analyzer generates two types of findings relevant to this solution. UnusedPermission findings identify roles with permissions that haven’t been exercised within the analysis period. UnusedIAMRole findings identify roles that haven’t been assumed at all. The Lambda function queries both finding types separately because they follow different remediation paths.

The Lambda function auto-detects the analyzer type at startup. When ANALYZER_SCOPE is set to organization, it checks for an ORGANIZATION_UNUSED_ACCESS analyzer first and falls back to ACCOUNT_UNUSED_ACCESS if none exists. If multiple analyzers of the same type exist in the account, the Lambda function selects the first active analyzer returned by the API. To target a specific analyzer, set the ANALYZER_ARN environment variable explicitly. With an organization-level analyzer, findings include roles from all member accounts. The Lambda function extracts the account ID from each finding’s resource ARN (for example, account 111122223333 from arn:aws:iam::111122223333:role/MyRole) and carries that context through the entire pipeline: attribution, remediation, and issue or PR creation all include the originating account.

For UnusedPermission findings, the Lambda function calls GenerateFindingRecommendation to initiate policy generation, then retrieves the IAM Access Analyzer-recommended policy through the GetFindingRecommendation API. This is a key integration point: IAM Access Analyzer provides the right-sized policy with unused permissions removed, so the automation doesn’t need to generate policies itself.

Here’s what a typical finding looks like for one of AnyCompany’s application roles:

{
  "id": "a1b2c3d4-5678-90ab-cdef-example11111",
  "resource": "arn:aws:iam::123456789012:role/AnyCompanyOrderProcessorRole",
  "findingType": "UnusedPermission",
  "analyzedAt": "2026-03-01T00:00:00Z",
  "unusedPermissions": [
    { "action": "s3:PutObject", "lastAccessed": null },
    { "action": "s3:DeleteObject", "lastAccessed": null },
    { "action": "s3:PutBucketPolicy", "lastAccessed": null },
    { "action": "dynamodb:DeleteItem", "lastAccessed": null }
  ],
  "activePermissions": [
    { "action": "s3:GetObject", "lastAccessed": "2026-02-28T14:30:00Z" },
    { "action": "s3:ListBucket", "lastAccessed": "2026-02-28T14:30:00Z" },
    { "action": "dynamodb:Query", "lastAccessed": "2026-02-28T12:00:00Z" }
  ]
}

The OrderProcessorRole has write and delete permissions for Amazon Simple Storage Service (Amazon S3) and Amazon DynamoDB, but only uses read operations. The IAM Access Analyzer recommendation removes the four unused actions while preserving the three active ones.

For UnusedIAMRole findings, no recommendation is needed: the role isn’t being assumed at all, so the remediation is to disable or delete it. The Lambda function caps the number of unused role issues per run (configurable using MAX_UNUSED_ROLE_ISSUES, default 10) to avoid overwhelming teams with a flood of issues on the first execution.

Role attribution using CloudTrail

For each finding, the Lambda function queries CloudTrail to determine how the role was created. The CreateRole event contains the information needed to classify the role’s origin.

An IaC-created role looks like this in CloudTrail:

{
  "eventName": "CreateRole",
  "userIdentity": {
    "type": "AWSService",
    "invokedBy": "cloudformation.amazonaws.com"
  },
  "requestParameters": {
    "roleName": "AnyCompanyOrderProcessorRole"
  },
  "userAgent": "cloudformation.amazonaws.com"
}

The cloudformation.amazonaws.com service principal and user agent tell the automation this role was created through a CloudFormation or AWS CDK deployment. The Lambda function then looks up the role’s tags to find the originating repository (stored in a Repository tag set during deployment).

A manually-created role looks different:

{
  "eventName": "CreateRole",
  "userIdentity": {
    "type": "IAMUser",
    "userName": "jstiles"
  },
  "requestParameters": {
    "roleName": "AnyCompanyIncidentResponseRole"
  },
  "userAgent": "console.amazonaws.com"
}

Here, the IAMUser type and console.amazonaws.com user agent indicate someone created this role through the console. Roles created through the AWS CLI show a similar pattern: the IAMUser type with a user agent like aws-cli/2.x.x. The automation classifies both console and AWS CLI-created roles as manually created, because neither has an IaC origin that can be updated programmatically. The automation captures the username and timestamp for the remediation issue.

Cross-account role attribution

When the Lambda function processes findings from an organization-level analyzer, the role might live in a different account than the one running the function. The automation handles this by assuming a cross-account role (configurable using CROSS_ACCOUNT_ROLE_NAME, defaulting to OrganizationAccountAccessRole) in the member account, then querying that account’s CloudTrail and IAM APIs for the CreateRole event. If the cross-account assume fails—because the role doesn’t exist in that account or permissions aren’t configured—the automation falls back gracefully, classifying the role as unknown origin and creating an issue with the account ID and available context. This approach helps the automation produce an actionable output for findings even when attribution is incomplete.

Policy recommendations and AWS CDK code generation

For IaC-managed roles with UnusedPermission findings, the Lambda function retrieves the IAM Access Analyzer-recommended policy and sends it to Amazon Bedrock to generate production-ready AWS CDK code. This is an important distinction: IAM Access Analyzer decides what the policy should be, and Amazon Bedrock wraps that policy in the AWS CDK constructs, imports, and resource definitions that the CI/CD pipeline needs to deploy the update.

The prompt instructs Amazon Bedrock to convert the recommended policy to AWS CDK code exactly as provided, with no modifications:

Generate Python CDK code that creates/updates the role with the
RECOMMENDED policy exactly as provided. Include proper imports
(aws_cdk, aws_iam), use CDK best practices (PolicyStatement,
proper resource ARNs), and add tags: ManagedBy=CDK,
RemediatedBy=AccessAnalyzer.

IAM Access Analyzer generates recommendations for both inline policies and customer managed policies. When a managed policy has partially unused permissions, the recommendation contains the full right-sized policy. The automation wraps this in AWS CDK code as an iam.ManagedPolicy construct. Note that if a managed policy is shared across multiple roles, the recommendation applies to the specific role’s usage pattern. In this case, the automation generates an issue for manual review rather than a PR, because modifying a shared policy could affect other roles.

The generated code goes through a validation step before inclusion in any PR. The Lambda function compiles the Python code to check for syntax errors and verifies that required AWS CDK patterns (iam, PolicyStatement) are present. If validation fails, the finding is logged as an error rather than creating a broken PR.

The solution doesn’t currently invoke the IAM Access Analyzer ValidatePolicy API to check the generated policy for errors or overly permissive statements. However, this is a natural extension point. Teams can add a validation step that calls ValidatePolicy on the Amazon Bedrock-generated policy before including it in a PR, detecting issues like missing resource constraints or invalid action names.

Amazon Bedrock also generates a plain-English explanation of the policy changes. For AnyCompany’s OrderProcessorRole, the explanation might read:

“The role currently has full S3 write access and DynamoDB delete permissions, but only uses read operations. Removing s3:PutObject, s3:DeleteObject, s3:PutBucketPolicy, and dynamodb:DeleteItem reduces the scope of impact if credentials are compromised, while preserving the s3:GetObject, s3:ListBucket, and dynamodb:Query permissions the application needs.”

The solution uses the Anthropic Claude Sonnet model on Amazon Bedrock for CDK code generation (where accuracy matters) and Claude Haiku on Amazon Bedrock for explanations (where speed and cost efficiency matter more).

Three-path remediation

The Lambda function evaluates each finding’s origin and routes it to one of three remediation paths.

Path 1: IaC-managed roles (pull request) – For AnyCompany’s OrderProcessorRole, the automation creates a PR in the originating repository. The PR includes:

  • The Amazon Bedrock-generated AWS CDK code implementing the IAM Access Analyzer-recommended policy
  • A policy diff showing exactly which permissions are being removed
  • The plain-English explanation of what the changes accomplish
  • Labels (security, iam-remediation, automated) for filtering and tracking

The team that owns the role reviews the PR through their normal code review process. Once merged, the fix deploys consistently across environments through the existing CI/CD pipeline.

Path 2: Manually-created roles (issue) – For AnyCompany’s IncidentResponseRole, the automation creates an issue that includes the Access Analyzer-recommended policy with unused permissions removed, a diff highlighting the changes, an Amazon Bedrock-generated explanation, and step-by-step guidance on importing the role into IaC. This gives the team an immediate remediation path (apply the recommended policy) while encouraging long-term governance through IaC adoption.

Path 3: Unused roles (soft-disable issue) – For roles that haven’t been assumed at all, the automation creates an issue recommending a three-stage decommission workflow: attach a deny-all policy to the role, monitor for 30 days to confirm no workload depends on it, then delete. This controlled approach reduces the risk of removing a role that’s used infrequently or seasonally – if something breaks during the monitoring period, removing the deny-all policy restores access immediately.

Dry-run mode

Before creating real PRs and issues, you can run the automation in dry-run mode by setting “dry_run": true in the CI/CD configuration or setting the CI_CD_PLATFORM environment variable to dryrun. In this mode, the Lambda function processes findings, classifies roles, and generates remediation data, but logs what it would create instead of making actual API calls to your repository platform. You can use the log to validate the automation’s behavior, review the classification accuracy, and tune exclusions before going live.

Operational metrics

The Lambda function publishes CloudWatch metrics after each run:

findings_processed Total UnusedPermission findings evaluated
iac_roles_found Roles classified as IaC-managed
manual_roles_found Roles classified as manually created
unused_roles_found Roles with no assume activity (UnusedIAMRole findings)
prs_created Pull requests created for IaC roles
issues_created Issues created (manual roles and unused roles)
errors Processing errors (failed classifications, API failures)

These metrics feed into dashboards and alarms. AnyCompany sets an alarm on errors > 5 to catch API throttling or configuration issues, and tracks prs_created + issues_created over time to measure remediation velocity.

Implementation

The solution ships as two AWS CDK stacks and deploys in minutes. The accompanying GitHub repository contains the complete source code, AWS CDK stacks, configuration templates, and step-by-step deployment instructions.

At a high level, deployment involves:

  1. Prerequisites: An AWS account with an ACCOUNT_UNUSED_ACCESS or ORGANIZATION_UNUSED_ACCESS analyzer enabled, Python 3.11 or later, AWS CDK v2, a CI/CD platform API token stored in AWS Secrets Manager, and Amazon Bedrock model access for the Anthropic Claude models you plan to use. The model IDs are configurable environment variables (BEDROCK_CODEGEN_MODEL and BEDROCK_EXPLANATION_MODEL); Amazon Bedrock retires older foundation models over time, so if the shipped defaults stop working, set these variables to current models you have enabled and redeploy. The repository README documents this.
  2. Configuration: Two files in the config/ directory control behavior. exclusions.json defines which roles and permissions to skip (break-glass roles, service-linked roles, tagged exceptions), and ci_cd_config.json configures your repository platform integration (GitLab or GitHub), labels, and throttling limits.
  3. Deploy: Run cdk deploy --all to create the Lambda function, EventBridge schedule, IAM roles, and CloudWatch alarms.
  4. Validate in dry-run mode: Start with “dry_run": true to see how the automation classifies your roles without creating real PRs or issues. Review the CloudWatch logs to confirm attribution accuracy and tune exclusions.
  5. Go live: Set “dry_run": false and redeploy. The Lambda function runs on schedule (daily by default) and begins creating PRs and issues.

The repository README covers each step in detail, including organization-wide deployment, cross-account configuration, and platform-specific setup for GitLab and GitHub.

Operational considerations

Deploying the automation is only the starting point. Running it in production means making decisions about how roles are retired, how the volume of findings is managed at scale, which roles warrant human review before any change is proposed, and how you measure the automation’s impact over time. The following practices keep remediation sustainable as your IAM footprint grows, so the automation reduces operational burden rather than adding to it.

Unused role lifecycle

Unused roles follow a three-stage decommission workflow. When the automation identifies a role that hasn’t been assumed within the analysis period, it creates an issue with the recommended decommission steps; the automation doesn’t modify the role directly. The team then follows the soft-disable approach:

  1. Attach a deny-all inline policy to the role. This blocks all actions without deleting the role or its existing policies.
  2. Monitor for 30 days. If a workload depends on the role (seasonal jobs, infrequent batch processes), the deny-all policy surfaces the dependency quickly. Removing the deny-all policy restores full access immediately; no need to recreate the role or reattach policies.
  3. Delete the role after the monitoring period confirms no impact.

This approach is deliberately conservative. Deleting a role is irreversible; you lose the trust policy, attached policies, and any resource-based policies that reference it. The soft-disable step gives teams a safety net while still making progress on reducing their unused role inventory.

Scaling and throttling

On AnyCompany’s first run, the automation found 47 unused permission findings and 4 unused roles. That’s manageable. But organizations with hundreds of accounts and thousands of roles might see significantly more findings on initial deployment.

This is especially true with an organization-level analyzer. A single-account deployment might surface dozens of findings; an organization-level analyzer across multiple accounts could surface hundreds or thousands on the first run. The throttling controls become critical at this scale.

Two throttling controls prevent the automation from overwhelming teams:

  • max_findings_per_run (default 50): Caps the total UnusedPermission findings processed per Lambda function execution. Remaining findings are picked up on the next scheduled run.
  • MAX_UNUSED_ROLE_ISSUES (default 10): Caps unused role issues per run. This is especially important during initial deployment when you might have a large backlog of roles that haven’t been assumed in months.

Start with conservative limits and increase them as your team builds confidence in the review process. A team that can review 10 PRs per week shouldn’t receive 50 on Monday morning.

Approval workflows for sensitive roles

Not every role should receive automated PRs. Roles with administrative permissions or access to sensitive data might warrant manual review before any remediation is created. The exclusion configuration supports this through the approval_required_for_tags field:

{
  "approval_required_for_tags": {
    "Sensitive": ["true"],
    "Admin": ["true"]
  }
}

Roles matching these tags generate issues for manual review instead of automated PRs, regardless of whether they’re IaC-managed. This gives security teams a checkpoint for high-risk roles while still automating remediation for standard application roles.

Monitoring and alerting

The metrics published after each Lambda function run (covered in the Technical details section) feed into CloudWatch dashboards and alarms. A few patterns worth setting up:

  • Alert on errors > 5 per run to catch API throttling, expired CI/CD tokens, or Amazon Bedrock availability issues.
  • Track prs_created + issues_created over time. A healthy trend shows this number decreasing as your environment converges toward least privilege.
  • Monitor unused_roles_found as a leading indicator. A sudden increase might signal a team spinning up roles for a project and not cleaning up afterward.
  • Compare iac_roles_found to manual_roles_found over time. As teams adopt IaC, the ratio should shift toward IaC-managed roles, which means more automated remediation and less manual work.

Cost

The solution uses Lambda (minimal cost at daily execution), CloudTrail (typically already enabled), IAM Access Analyzer (charges per IAM role or user analyzed per month for the unused access analyzer), and Amazon Bedrock (pay-per-token for AWS CDK code generation and explanations). For most organizations the ongoing cost is low, and Amazon Bedrock token usage is the largest variable, scaling with the number of findings processed per day and the complexity of each policy. Review the pricing pages for each service for current rates.

For organization-level deployments, the IAM Access Analyzer cost scales with the number of IAM roles analyzed across all member accounts. The ORGANIZATION_UNUSED_ACCESS analyzer charges per role per month across the organization, so an organization with 500 roles across 20 accounts will see higher analyzer costs than a single account with 50 roles. Review the IAM Access Analyzer pricing page for current rates.

Cleanup

To remove the solution, run cdk destroy --all from the infrastructure/ directory. This removes the Lambda function, EventBridge rule, CloudWatch alarms, and IAM roles created by the stacks.

If you stored a CI/CD platform API token in Secrets Manager as part of deployment, delete it with aws secretsmanager delete-secret --secret-id <your-secret-name> --recovery-window-in-days 7. The 7-day recovery window lets you restore the secret if the deletion was accidental. After 7 days, the secret is permanently deleted and can’t be recovered. To delete immediately without a recovery window, add --force-delete-without-recovery.

Lambda automatically creates a CloudWatch Logs log group at /aws/lambda/<function-name> that persists after cdk destroy --all and continues to incur log storage charges. To remove it, run aws logs delete-log-group --log-group-name /aws/lambda/<function-name>. WARNING: This permanently deletes all execution logs.

The IAM Access Analyzer isn’t created by the AWS CDK stacks. WARNING: Deleting the analyzer permanently removes all findings, analysis history, and unused permission data. Export any findings you need to retain before deletion. After exporting, run aws accessanalyzer delete-analyzer --analyzer-name <your-analyzer-name> to delete it. The ACCOUNT_UNUSED_ACCESS and ORGANIZATION_UNUSED_ACCESS analyzer types incur charges based on the number of IAM roles and users analyzed per month.

If you deployed in organization mode and created cross-account roles (default name: OrganizationAccountAccessRole) in member accounts solely for this solution, remove them from those accounts.

Any PRs or issues already created in your CI/CD platform remain after stack deletion; they’re artifacts in your repository, not AWS resources. See the repository README for detailed cleanup instructions.,

Conclusion

Automating IAM permission remediation turns least privilege from a periodic compliance exercise into an operational practice. By connecting IAM Access Analyzer findings and recommendations to your CI/CD pipeline, remediation shifts from manual security tasks to code review processes that your teams already follow.

The three-path strategy acknowledges how infrastructure evolves. IaC-managed roles receive pull requests with production-ready AWS CDK code and plain-English explanations. Manually created roles receive actionable issues with recommended policies and IaC migration guidance. Unused roles are put on a controlled decommission path that protects against accidental disruption. Over time, the manual role count decreases as teams adopt IaC, and remediation becomes a routine part of your deployment pipeline.

Start with a pilot. Choose 10–20 non-production roles, deploy in dry-run mode, and review the classification results. Tune your exclusions, confirm the CloudTrail attribution is accurate for your environment, and then enable live remediation. Expand to production roles after your team is comfortable with the review cadence.

When you’re ready to scale beyond a single account, switch to an organization-level analyzer and the same Lambda function will process findings across all member accounts with no architectural changes required, only a configuration toggle.

The complete source code, AWS CDK stacks, and configuration templates are available in the accompanying GitHub repository.

If you have feedback about this post, submit comments in the Comments section below.


Luis Pastor

Luis E Pastor

Luis is a Senior Security Solutions Architect at AWS specializing in infrastructure security, compliance, and generative AI security. He leads technical field communities focused on security and compliance while contributing to AWS Well-Architected Framework guidance. Before AWS, he helped clients across financial services, healthcare, and retail industries improve their security posture in hybrid environments. Outside of work, Luis enjoys staying active and culinary adventures.

Rodolfo Brenes

Rodolfo Brenes

Rodolfo is a Principal Solutions Architect focused on Cloud Governance and Compliance. With over 18 years of experience, he currently leads a technical field community in AWS helping customers scale and improve their security and governance frameworks. Besides work, Rodolfo enjoys video games, playing with his four cats, and won’t say no to a good outdoor adventure.

Sowjanya Rajavaram

Sowjanya Rajavaram

Sowjanya is a Sr Solution Architect who specializes in Identity and Security in AWS. Her entire career has been focused on helping customers of all sizes solve their identity and access management problems. She enjoys traveling and experiencing new cultures and food.

Satish Uppalapati

Satish is an Associate Assurance Consultant with AWS Security Assurance Services (SAS) and has more than 8 years of experience in IT risk, governance, and regulatory assurance. He works with AWS customers to align cloud environments with multiple frameworks. Satish helps organizations build security and governance programs that meet regulatory objectives while supporting business operations. He also focuses on advancing governance for AI systems, including emerging standards.

How to build a serverless mass email solution with Amazon SES

Post Syndicated from Brad Watson original https://aws.amazon.com/blogs/messaging-and-targeting/how-to-build-a-serverless-mass-email-solution-with-amazon-ses/

Sending mass email campaigns presents significant challenges for many organizations. Enterprises often spend millions annually on proprietary email systems that are inflexible and expensive to maintain. These legacy platforms can restrict sending capacity, offer limited control, and require costly licensing agreements. The challenges intensify when handling large-scale communications like automated notifications, bulk marketing campaigns, and system-generated alerts. These scenarios create reliability issues, scaling limitations, and rising costs that impact teams’ ability to communicate effectively with customers.

Recently, a large federal organization faced similar challenges, spending over a million dollars annually on their email campaigns. By building a custom email solution on AWS, they sent a 2 million email campaign for approximately $300. This cost includes Amazon Simple Email Service (Amazon SES) and other AWS services. This transformation cut costs while providing the scalability and flexibility they needed for their growing campaign needs.

This transformation succeeded because building a cloud-native serverless mass email solution offers several advantages:

  • Cost optimization.
    • Pay only for email sent and actual compute resources used.
    • Remove costs associated with managing email servers.
    • Remove expensive licensing fees and maintenance overhead.
  • Scalability and reliability.
    • Automatically handle varying email volumes without infrastructure changes.
    • Support reliable delivery through built-in retry mechanisms and error handling.
    • Perform consistently during peak sending periods.
  • Security and compliance.
    • Secure access control through AWS Identity and Access Management (IAM) roles with least-privilege principles.
    • Comprehensive audit trails for all email campaigns with detailed logging to support your reporting requirements.
    • Detailed logging that customers can use for their compliance and reporting requirements.
    • Data encryption in transit and at rest that you can configure.

In this post, we explore the architecture of a cloud-native serverless mass email solution that integrates Amazon SES with AWS Step Functions, Amazon API Gateway, and Amazon DynamoDB. You will learn how these services work together to process email campaigns at scale while minimizing cost. Let’s get started!

Solution overview

The serverless mass email solution consists of two main components: a user-friendly frontend interface and a scalable serverless backend. The frontend operates completely independently from the backend processing system, communicating through RESTful APIs from Amazon API Gateway. With this architecture, you can use the provided frontend interface as-is. Alternatively, you can integrate your own custom UI or existing applications while using the same backend email processing infrastructure.

The following diagram shows the complete architecture of the serverless mass email solution, including how the frontend and backend components connect through API Gateway to process email campaigns.

Complete serverless mass email architecture, with the frontend and backend connected through Amazon API Gateway

Figure 1: Complete architecture

Frontend architecture and user flow

The frontend of the solution prioritizes usability while providing email campaign capabilities. Here’s how the components work together:

Frontend architecture: web interface, Amazon Cognito authentication, and requests through API Gateway to AWS Lambda

Figure 2: Frontend architecture of the SES email application

  1. Login – Users navigate to the web interface URL (hosted on Amazon Simple Storage Service (Amazon S3)) which prompts them to authenticate.
  2. User authentication – Amazon Cognito handles authentication, providing secure user management and restricting access to authorized users.
  3. User interface – After successful authentication, users are redirected to a graphical user interface (GUI) where they can design and save email templates and launch large-scale campaigns (refer to figures 3 and 4).
    1. Templates.
      1. Amazon SES supports two types of templates: stored and inline. Stored templates live in SES, and you can reuse them across campaigns. With inline templates, you define the content and variables directly in the email sending request. Both approaches support dynamic personalization by replacing variables with recipient-specific data when the email is sent. For example, you can create a template that personalizes each email with the recipient’s name, custom offers, or any other dynamic content. For detailed information about template capabilities and personalization options, refer to the Amazon SES template documentation.

The following screenshots show the campaign interface, the template creation interface, and the campaign monitoring interface.

Email template creation interface of the mass email application

Figure 3: Email template creation interface

Mass email campaign interface of the application

Figure 4: Mass email campaign interface

Campaign monitoring interface showing the delivery status of a mass email campaign

Figure 5: Campaign monitoring interface

  1. Request processing – Each user action triggers a secure request through Amazon API Gateway to AWS Lambda functions, which then coordinate with our backend processing system.

From the user’s perspective, the experience is similar to using any standard email platform, with the added capability of handling campaigns at scale. This interface helps marketing teams, customer success managers, and business operations staff create and launch email campaigns directly through their browser, without needing to understand complex email protocols.

Backend architecture

After a user initiates an email campaign, our backend orchestrates a series of steps to facilitate reliable, large-scale email delivery. Let’s follow how an email campaign flows through the system:

Backend architecture: Step Functions orchestrates batching, Lambda sends email through Amazon SES, and DynamoDB logs delivery attempts

Figure 6: Backend architecture of the SES email application

As shown in the preceding figure, the backend processes email campaigns through the following steps:

  1. Email campaign processor – When a user creates a new campaign through the GUI, a Lambda function processes the initial request, taking the user’s selected email template and campaign parameters. The function then triggers an AWS Step Functions workflow.
  2. Workflow orchestration – The Step Functions workflow acts as the conductor and coordinates the entire email sending process. It initializes the campaign, sets up necessary configurations, and organizes the campaign into manageable batches.
  3. Recipient processing – Before sending email, the Step Functions workflow retrieves recipient information, including the recipient’s name and email address, from DynamoDB and checks it for accurate delivery details.
  4. Batch email processing – The Step Functions workflow begins organizing the email into manageable batches. The workflow queues these batches in Amazon Simple Queue Service (Amazon SQS), preparing them for processing.
  5. Batch monitoring – As batches move through the system, Step Functions actively monitors their progress, tracking the status of each batch throughout the sending process.
  6. Email sending – When SQS receives a message, it invokes a Lambda function that sends the email to Amazon SES for delivery. The function logs each delivery attempt in DynamoDB, with failed deliveries automatically returning to the SQS queue for retry attempts. It also records successful deliveries to support idempotency and prevent duplicate sends.
  7. Record management – DynamoDB stores an audit trail that tracks both successful and failed delivery attempts, providing detailed logs to support reporting, campaign performance assessments, and compliance efforts.

Using these AWS services, the solution automatically scales from sending a few email to millions without manual intervention or infrastructure provisioning. You pay only for what you use, with no idle server costs. To demonstrate the cost-effectiveness of this architecture: sending 10,000 email costs approximately USD $4, including all AWS service charges. For current pricing details, refer to Amazon SES pricing.

To deploy this solution in your AWS account, refer to the source code on GitHub.

Conclusion

In this post, we explored the architecture of a scalable email sending solution using Amazon SES and other AWS serverless services. This architecture removes the complexity of traditional email infrastructure while providing capabilities for handling large-scale email campaigns. Whether you’re looking to modernize your existing email infrastructure or stand up a new solution, this serverless approach offers the ideal combination of streamlined design, scalability, and cost-effectiveness.

Additional resources


About the authors

Extend Amazon Bedrock Guardrails to Tool Interactions Using the Strands Agents SDK

Post Syndicated from Stephan Traub original https://aws.amazon.com/blogs/security/extend-amazon-bedrock-guardrails-to-tool-interactions-using-the-strands-agents-sdk/

If you’re running AI agents in production, Amazon Bedrock Guardrails protects the model boundary. But your agents also invoke tools, fetch external data, and communicate with other systems. That data flows outside the model boundary, where model-level guardrails can’t reach.

You can extend guardrail coverage to those interactions using three validation checkpoints built with the Strands Agents SDK lifecycle hooks and Amazon Bedrock guardrails. You implement each checkpoint using a Strands life-cycle hook, which validates data at a critical trust boundary without changing your existing tools or agent logic.

Agents can communicate with other systems through the Model Context Protocol (MCP), a standard for connecting AI systems to data sources and tools. You will learn how to implement three validation checkpoints, scope different guardrails to specific tools, and scale them to other agents.

Extending guardrails beyond the model boundary

Amazon Bedrock Guardrails provides protection at the model boundary. Every model invocation is checked: the input prompt is validated before inference, and the model response is validated after inference. You can enforce guardrail use at the account level using AWS Identity and Access Management (IAM) policies, making guardrails mandatory for model calls across your account. You can further refine this by using Amazon Bedrock Guardrails input tagging to mark specific portions of the prompt for evaluation, so trusted content like system prompts can be skipped.

Guardrails cover what the model sees, but agents do more than call models. They invoke tools, pull data from external sources, communicate with MCP servers, and return results to users. These interactions happen outside the model boundary by design, because model-level guardrails focus on the prompts and responses the model itself handles. Adding validation at the tool boundary complements, rather than replaces, that model-level protection.

Model-level guardrails alone leave you exposed in four ways:

  • Tool parameters pass through unchecked. The model decides which tool to use and what parameters to pass. The agent then calls the tool with those parameters. No validation sits between the model’s decision and the tool’s execution. If the parameters inadvertently contain personally identifiable information (PII) or policy-violating content, the tool runs with that content.
  • External data enters without validation. Agents consume data from tool responses, MCP server outputs, and API calls. Without validation at the tool boundary, content from external sources can influence the agent’s behavior before model-level guardrails have a chance to evaluate it.
  • Misleading content can affect reasoning. An agent that retrieves inaccurate or misleading content from an external source might treat it as authoritative, producing skewed recommendations in lending, healthcare, or legal advice.
  • Multi-agent systems can spread bad data downstream. In multi-agent systems, a misconfigured or poorly designed upstream component can pass policy-violating content to downstream agents. Model-level guardrails at each agent’s boundary don’t inspect data flowing between agents at the tool layer.

Three validation checkpoints

To close these gaps, add three validation checkpoints at each trust boundary where data crosses into or out of your agent as shown in Figure 1.

  • Checkpoint 1: Inbound data validation – Check data before it reaches the model—user input, data from other agents, MCP tool servers, and RAG pipelines. You catch policy-violating or biased content before it enters the model’s context window. In the Strands Agents SDK, you implement this using a BeforeInvocationEvent hook that fires before model inference or tool execution occurs. The hook inspects incoming messages and blocks the request if the content violates policies. The model doesn’t see blocked content.
  • Checkpoint 2: Tool interaction supervision – Before the agent calls a tool, a BeforeToolCallEvent hook checks the parameters it’s about to pass. This is the gap model-level guardrails don’t cover. The model has already decided what to send, but nothing has verified whether that content is safe to act on. If the hook flags the input, the call is canceled before the real-world action occurs.
  • Checkpoint 3: Outbound data validation – Validate results before returning them to the user or passing them to downstream systems. You need this most for tools that ingest external content, like a web search tool fetching web pages from sites outside your control. In Strands, an AfterToolCallEvent hook validates the tool’s return value and replaces it with a block message if the content violates policies.
Figure 1: Three validation checkpoints extend Amazon Bedrock Guardrails from the model boundary to the tool boundary.

Figure 1: Three validation checkpoints extend Amazon Bedrock Guardrails from the model boundary to the tool boundary.

You can adjust the validation intensity of each checkpoint:

  • At Checkpoint 1, use a full Amazon Bedrock guardrail with PII detection, content filtering, and topic enforcement.
  • Checkpoint 2 can be lighter. Configure a separate Amazon Bedrock guardrail with rules tailored to the specific tool being called, or run local checks like regex validation or schema enforcement.
  • For Checkpoint 3, focus on unwanted content detection for tool outputs that return external data.

Mix fast deterministic checks (regex, schema validation, allowlists) with AI-based guardrail evaluations. This keeps latency low.

Implementation

The implementation uses boto3, the AWS SDK for Python, to call the ApplyGuardrail API. The Strands Agents SDK exposes one life-cycle event per checkpoint. Here’s how to implement each one.

Prerequisites

This post assumes you already have a working Strands agent. Your agent should use least-privilege tool access, scoped system prompts, and validated business logic. If you’re starting from scratch, see Strands Agents SDK: A technical deep dive into agent architectures and observability for a step-by-step walk through of building and deploying a Strands agent with Amazon Bedrock Agent Core.

Before implementing the multi-checkpoint approach, you’ will need:

  1. An AWS account with access to Amazon Bedrock
  2. Amazon Bedrock Guardrails configured (see Creating a guardrail)
  3. Python 3.11 or later installed
  4. The Strands Agents SDK installed: pip install strands-agents
  5. AWS credentials configured with permissions for bedrock:ApplyGuardrail and bedrock:InvokeModel
  6. Your guardrail ID and version from the AWS Management Console for Amazon Bedrock (navigate to Guardrails, select your guardrail, and copy the ID)

Create the guardrail validation hook

The GuardrailHook class is a Strands HookProvider. It registers three callbacks, one for each lifecycle event. When Strands triggers an event, the matching callback runs validate_inbound checks user messages, validate_input checks tool parameters before execution, and validate_output checks tool results. All three use the shared _check method, which calls the Amazon Bedrock ApplyGuardrail API.

Create a guardrail_hook.py file and add this implementation. Use the optional tool_names parameter to scope a hook to specific tools, or pass None to apply it everywhere:

import boto3
from strands.hooks import HookProvider, HookRegistry
from strands.hooks.events import (
    BeforeInvocationEvent,
    BeforeToolCallEvent,
    AfterToolCallEvent,
)

class GuardrailHook(HookProvider):

    def __init__(self, guardrail_id, guardrail_version, region_name, tool_names=None):
        self.client = boto3.client("bedrock-runtime", region_name=region_name)
        self.guardrail_id = guardrail_id
        self.guardrail_version = guardrail_version
        self.tool_names = tool_names  # None = apply to all tools

    def register_hooks(self, registry: HookRegistry, **kwargs):
        registry.add_callback(BeforeInvocationEvent, self.validate_inbound)
        registry.add_callback(BeforeToolCallEvent, self.validate_input)
        registry.add_callback(AfterToolCallEvent, self.validate_output)

    def _check(self, content, source="INPUT"):
        """Call Bedrock ApplyGuardrail. Returns True if content is safe."""
        response = self.client.apply_guardrail(
            guardrailIdentifier=self.guardrail_id,
            guardrailVersion=self.guardrail_version,
            source=source,       # "INPUT" applies input policies; "OUTPUT" applies output policies
            content=[{"text": {"text": content}}],
        )
        return response["action"] != "GUARDRAIL_INTERVENED"

    # Checkpoint 1 — BeforeInvocationEvent
    # Validates user input before model inference or tool execution occurs.
    # The model does not see blocked content.
    async def validate_inbound(self, event: BeforeInvocationEvent):
        for msg in reversed(event.messages):
            if msg.get("role") == "user":
                for block in msg.get("content", []):
                    text = block.get("text", "")
                    if text and not self._check(text):
                        event.messages.clear()
                        event.messages.append({
                            "role": "user",
                            "content": [{"text": "Request blocked by safety guardrail."}],
                        })
                        return
                break

    # Checkpoint 2 — BeforeToolCallEvent
    # Validates tool input parameters before the tool executes.
    # Skips tools not in tool_names (if a filter is set).
    async def validate_input(self, event: BeforeToolCallEvent):
        if self.tool_names and event.tool_use.get("name") not in self.tool_names:
            return
        tool_input = event.tool_use.get("input", {})
        for param_value in tool_input.values():
            if isinstance(param_value, str) and not self._check(param_value):
                event.cancel_tool = "This request was blocked by a safety guardrail."
                return

    # Checkpoint 3 — AfterToolCallEvent
    # Validates tool output before it reaches the agent.
    # Skips tools not in tool_names (if a filter is set).
    async def validate_output(self, event: AfterToolCallEvent):
        if self.tool_names and event.tool_use.get("name") not in self.tool_names:
            return
        content_parts = [
            block["text"]
            for block in event.result.get("content", [])
            if "text" in block
        ]
        content = "\n".join(content_parts)
        if content and not self._check(content, source="OUTPUT"):
            event.result = {
                "toolUseId": event.result["toolUseId"],
                "status": "error",
                "content": [{"text": "Content blocked by safety guardrail."}],
            }

Define tools

Strands discovers tools through the @tool decorator. The decorator turns a plain Python function into a tool the model can call, using the function’s docstring and type hints as the tool’s contract. Here are two simple examples used in the registration sections below. A web search tool and a customer data tool:

from strands import tool

@tool
def web_search(query: str) -> str:
    """Search the web and return a result snippet."""
    # Replace with your actual search implementation
    return f"Search results for: {query}"

@tool
def get_customer_data(customer_id: str) -> str:
    """Retrieve customer record by ID."""
    # Replace with your actual data lookup implementation
    return f"Customer record for: {customer_id}"

If you don’t have existing tools, create a tools.py file and copy in the example code above.

Register the hook

Strands activates hooks through the hooks parameter on the Agent constructor. After being registered, the hook’s callbacks run automatically on every matching lifecycle event. No changes are needed in your tools or agent logic. For a single guardrail applied to all tools, create one hook instance and pass it to your agent:

from strands import Agent
from strands.models import BedrockModel
from guardrail_hook import GuardrailHook
from tools import web_search, get_customer_data # Example tools - replace with your tools

# Example model and region selection
model = BedrockModel(
    model_id="us.anthropic.claude-sonnet-4-5",
    region_name="us-east-1",
)

guardrail_hook = GuardrailHook(
    guardrail_id="your-guardrail-id",    # Copy it from the Amazon Bedrock console > Guardrails
    guardrail_version="1",               # Use "DRAFT" for testing
    region_name="us-east-1",             # Region where the guardrails are defined
)

agent = Agent(
    model=model,
    tools=[web_search, get_customer_data], # Example tools
    system_prompt="You are a helpful assistant.", # Example system prompt
    hooks=[guardrail_hook],  # Applied to all tool calls
)

Use different guardrails per tool

Different tools carry different risks. A web search tool fetches external content from untrusted sites and needs strict output filtering. A customer data tool returns internal records and might need PII detection configured differently. The tool_names parameter scopes a hook to specific tools. Strands still runs every registered hook on each event, but hooks skip the call when the tool name doesn’t match. Register one hook per guardrail:

from strands import Agent
from strands.models import BedrockModel
from guardrail_hook import GuardrailHook
from tools import web_search, get_customer_data # Example tools - replace with your tools

# Example model and region selection
model = BedrockModel(
    model_id="us.anthropic.claude-sonnet-4-5",
    region_name="us-east-1",
)
# Strict content filtering and PII detection for web search results
web_search_hook = GuardrailHook(
    guardrail_id="gr-websearch-id",      # Guardrail ID with content filtering + PII detection
    guardrail_version="1",               # Or set to DRAFT
    region_name="us-east-1",             # Change to your region
    tool_names={"web_search"},           # Only applies to the web_search tool
)

# PII detection for customer data — prevents sensitive records from leaking into tool parameters
customer_data_hook = GuardrailHook(
    guardrail_id="gr-customerdata-id",   # Guardrail ID with PII detection
    guardrail_version="1",               # Or set to DRAFT
    region_name="us-east-1",             # Change to your region
    tool_names={"get_customer_data"},    # Only applies to the get_customer_data tool
)

agent = Agent(
    model=model,
    tools=[web_search, get_customer_data],        # Example tools
    system_prompt="You are a helpful assistant.", # Example system prompt
    hooks=[web_search_hook, customer_data_hook],  # Each hook runs only for its assigned tools
)

Each guardrail is configured independently in the Amazon Bedrock console. You can match validation strictness to each tool’s risk level instead of applying one policy across your entire agent.

Test your implementation

Run a quick test with the preceding examples:

  1. Create a project folder and add the following files:
    1. guardrail_hook.py the GuardrailHook class
    2. tools.py the web_search and get_customer_data tool definitions as examples
    3. agent.py the agent setup from the Register the hook section
  2. In agent.py, add a test prompt at the end:
# Send a test prompt
response = agent("Search the web for the latest news on AI security.")
print(response)

  1. Update the guardrail IDs, AWS Region, and model ID in agent.py to match your configuration.
  2. Run the agent from your project folder: python agent.py

The guardrail hook runs at each checkpoint. If the prompt or any tool output is flagged, you’ll see the block message in the response instead of the tool result.

Use the hook across your organization

The GuardrailHook is a standalone HookProvider. Build it once, then attach it to Strands agents by passing it to the hooks parameter. The same hook package can be published as an internal library and consumed by

You can swap guardrail configurations or add checks like regex or schema validation without touching agent or tool code.

Conclusion

Amazon Bedrock Guardrails protects the model boundary, but agents also call tools, consume external data, and return results that never pass through model-level checks. The three validation checkpoints in this post close that gap using Strands Agents SDK lifecycle hooks: BeforeInvocationEvent validates user input, BeforeToolCallEvent validates tool parameters, and AfterToolCallEvent validates tool output. The same GuardrailHook class supports one shared guardrail or different guardrails scoped per tool, and deploys unchanged from local testing to Amazon Bedrock Agent Core Runtime.

To learn more, see:

If you have feedback about this post, submit comments in the Comments section below.


Stephan Traub

Stephan Traub

Stephan is a senior security consultant with AWS Professional Services, where he works closely with customers across different industries. A true technology enthusiast, Stephan is passionate about empowering customers to achieve a robust security posture within their cloud environments and AI workloads. When Stephan isn’t immersed in his AWS work, you can find him on the volleyball court or exploring the world with his family.

Migrate an OAuth 2.0 authenticated Apache Kafka cluster to Amazon MSK with MSK Replicator

Post Syndicated from Subham Rakshit original https://aws.amazon.com/blogs/big-data/migrate-an-oauth-2-0-authenticated-apache-kafka-cluster-to-amazon-msk-with-msk-replicator/

In an earlier post, we walked through how Amazon Managed Streaming for Apache Kafka (Amazon MSK) Replicator migrates external and self-managed Apache Kafka clusters to Amazon MSK. It replicates your topics and their configurations, keeps topic and consumer-group names intact, and synchronizes consumer-group offsets, so your producers and consumers can cut over on their own schedule instead of all at once. MSK Replicator now supports OAuth 2.0 (SASL/OAUTHBEARER) authentication to the external cluster, and that is what this post covers.

If your external Kafka cluster authenticates clients with OAuth, MSK Replicator can connect to it, but “OAuth” isn’t a single thing you switch on. It’s a family of grant types, and each one comes with its own trust model, its own set of inputs you need to supply, and its own configuration on both the Replicator side and your identity provider (IdP) side.

In this post, we walk you through the grant types one by one, show you how to configure Replicator for each, call out the network and TLS prerequisites that are commonly missed, and finish with how to handle IdPs that sit behind an additional identity layer. This mechanism works with any OAuth 2.0 (OIDC) identity provider, including Keycloak, Okta, Microsoft Entra ID, PingFederate, and Auth0. OAuth here governs only how Replicator authenticates to your external cluster, so the target can be either Amazon MSK Standard or Express brokers, which always use IAM.

How OAuth authentication works

Before you configure Replicator, it helps to be precise about how the OAuth Kafka handshake works.

The components

  • The Identity Provider (IdP) – Issues access tokens and publishes the public keys. Brokers use these keys to verify the tokens. Examples: Keycloak, Okta, Microsoft Entra ID, PingFederate, Auth0, or a custom OIDC server.
  • The client – In our case, MSK Replicator, acting as a Kafka consumer/producer against your external cluster.
  • The resource server – Your self-managed Kafka broker, which must decide whether to admit a connection.
  • The access token – A JWT (JSON Web Token): a base64url-encoded, three-part string header.payload.signature that the IdP cryptographically signs.

The SASL/OAUTHBEARER handshake, step by step

The following sequence diagram shows the full exchange, from Replicator requesting a token to the broker accepting the connection:

Sequence diagram of the SASL/OAUTHBEARER handshake: Replicator requests a token from the IdP, receives a signed JWT, presents it to the Kafka broker, and the broker verifies the JWT against cached JWKS keys before accepting the connection.

Figure 1: The SASL/OAUTHBEARER handshake. Replicator gets a signed JWT from the IdP and presents it to the broker, which verifies it against cached JWKS keys before accepting the connection.

Walking through it:

  1. Request a token – Replicator asks the IdP for an access token. The exact request depends on the grant type (covered in the next section).
  2. Receive a signed JWT – The IdP returns a signed JWT access token.
  3. Present the token – Replicator opens a SASL/OAUTHBEARER connection to the external Kafka brokers and presents the JWT.
  4. Verify locally – The broker verifies the JWT signature against the IdP’s cached JWKS public keys, without calling the IdP per message.
  5. Connection accepted – The broker admits the connection and derives the Kafka principal from the preferred_username claim.

Step 4 is worth dwelling on: the broker validates the token locally. It fetches the IdP’s JWKS (JSON Web Key Set, the public half of the IdP’s signing keys, RFC 7517) from an endpoint like https://idp.example.com/realms/kafka/protocol/openid-connect/certs and caches it, refreshing on a configurable interval (and re-fetching if it sees a key ID it doesn’t recognize). Incoming JWT signatures are then verified against those cached keys. The IdP is not in the hot path of message traffic. It is contacted only to (a) issue tokens to clients, and (b) serve its public keys for the periodic JWKS refresh.

What the Kafka broker checks

When Replicator presents a JWT, the broker validates:

  • Signature – Proves the IdP issued the token and no one tampered with it (verified against JWKS).
  • iss (issuer) – Must match the broker’s configured oauth.valid.issuer.uri, byte-for-byte, including scheme, host, port, and path. A mismatch is a common configuration error.
  • exp (expiry) – Expired tokens are rejected. Strimzi’s client callback handler proactively refreshes before expiry, so you shouldn’t see mid-stream failures.
  • The principal claim – Typically preferred_username. The broker uses this as the Kafka principal in ACLs (for example, User:service-account-msk-replicator). This matters: the identity Replicator authenticates as on the external cluster must have ACLs that you configure to grant it the read/describe permissions it needs.

Mapping your IdP to a Replicator grant type

A grant type is the protocol by which the client proves its identity to the IdP and obtains a token. This is the front half of the preceding handshake (steps 1 and 2). MSK Replicator supports three of them. You already know how your Kafka clients authenticate to your IdP today, so start from that.

Which grant to use?

Find the row that matches how your clients get tokens today:

How your Kafka clients get tokens from the IdP today Grant type Long-lived secret? What you trust/register on the IdP
A client_id / client_secret (confidential client) CLIENT_CREDENTIALS Yes (stored on AWS Secrets Manager) Nothing new: reuse the existing client, or create one for Replicator
You want secretless, and your IdP can trust an external token issuer IAM_JWT_BEARER No AWS STS as an external token (OIDC) issuer. Trust its JWKS
You want secretless, and your IdP models workloads as signed-JWT clients CLIENT_CREDENTIALS_ASSERTION No AWS STS as the client’s signing authority (private_key_jwt). Trust its JWKS

The simplest mapping is like-for-like: if your clients use a client_id/client_secret, point Replicator at the same client with CLIENT_CREDENTIALS. If you’d rather not give Replicator a long-lived secret, the two secretless grants let it authenticate with its AWS identity instead. Choose between them based on how your IdP prefers to trust an external party.

The rest of this section explains why the three grants differ, using an analogy. If your row is clear and you only want the configuration, skip ahead to Configuring and creating the replicator.

A scenario: checking in at a secure office building

A visitor needs to get into a secure office building. They can’t walk straight in. First they stop at the reception desk to prove who they are and collect a temporary access pass. Only then can they use that pass at the building’s turnstile to get inside. In OAuth terms: the building is your external Kafka cluster, the reception desk is the IdP, the temporary access pass is the access token (JWT), and the visitor is MSK Replicator. Presenting the pass at the turnstile is the SASL/OAUTHBEARER step, and it works the same way for every grant type. What differs is how the visitor proves who they are at the reception desk before it prints a pass.

Scenario 1: CLIENT_CREDENTIALS (the shared PIN)

CLIENT_CREDENTIALS scenario shown as a visitor entering a building: the visitor authenticates at reception with a PIN (the client secret), receives a temporary badge (the access token), and uses it to enter the building (the Kafka cluster).

Figure 2: CLIENT_CREDENTIALS. The visitor authenticates at reception with a PIN (the client_secret), gets a temporary badge (the access token), and uses it to enter the building (the Kafka cluster).

At the reception desk the visitor keys in a PIN the desk already have on file (the client_secret), collects a temporary access pass in return (the access token), and uses that pass to get into the building. Both sides hold the same secret. In practice (RFC 6749 §4.4), Replicator authenticates to the IdP with a client_id/client_secret stored on AWS Secrets Manager, receives the access token, and presents it to the external Kafka brokers over SASL/OAUTHBEARER. Use it when your IdP already issues client secrets for machine clients. This is usually a like-for-like move that reuses the client your existing producers and consumers use, or a new one created for Replicator.

Scenario 2: IAM_JWT_BEARER (the badge is the request)

IAM_JWT_BEARER scenario: the visitor presents an employer-signed badge (an STS JWT) to reception as the request itself and receives an access token, because reception trusts the employer’s stamp (the STS JWKS).

Figure 3: IAM_JWT_BEARER. The visitor shows an employer-signed badge (an STS JWT) to reception as the request itself and gets an access token. Reception accepts it because it trusts the employer’s stamp (the STS JWKS).

First, the visitor collects an employer-signed badge: Replicator calls STS GetWebIdentityToken to mint an STS JWT. At the reception desk the badge itself is the request. The visitor shows it to ask for a pass. Reception trusts the employer’s tamper-proof stamp (STS JWKS), so it accepts the badge and prints a temporary access pass. In practice (RFC 7523 §2.1), the STS JWT is sent as the authorization grant (assertion), and the IdP trusts AWS STS as an external token issuer. Use it when you want secretless authentication, and your IdP can trust an external issuer’s JWTs.

Scenario 3: CLIENT_CREDENTIALS_ASSERTION (the same badge, used as ID on the form)

CLIENT_CREDENTIALS_ASSERTION scenario: the visitor fills out reception’s standard request form and attaches the same STS JWT as identification to receive an access token, which reception grants by trusting the employer’s stamp (the STS JWKS).

Figure 4: CLIENT_CREDENTIALS_ASSERTION. The visitor fills out reception’s standard request form and attaches the same STS JWT as ID, getting an access token. Reception trusts the employer’s stamp (the STS JWKS).

The visitor again collects the same employer-signed badge (STS JWT). This time they fill out the reception desk’s standard access request form (the client_credentials grant) and attach the badge to it as identification, all in one submission. Reception trusts the same employer stamp (STS JWKS) and prints a temporary access pass. In practice (RFC 7521/RFC 7523 §2.2), the same STS JWT is sent as the client_assertion on the client_credentials grant, with the IdP trusting STS as the client’s signing authority (private_key_jwt). Use it when you want secretless authentication and your IdP models external workloads as signed-JWT clients.

Scenarios 2 and 3 in one sentence. Both mint the same STS JWT and share the same benefit: nothing shared can leak, because there is no secret. They differ only in where the STS JWT sits in the token request. IAM_JWT_BEARER sends it as the assertion (the badge is the request), while CLIENT_CREDENTIALS_ASSERTION sends it as the client_assertion on a standard client_credentials request (the badge is ID on the form). That single difference is what you register on the IdP: AWS STS as an external token issuer, or as the client’s signing authority.

Solution overview

Now that you can map your setup to a grant type, the next question is where these pieces actually run. MSK Replicator runs on AWS managed infrastructure but attaches elastic network interfaces (ENIs) into the subnets of the target Amazon MSK cluster’s virtual private cloud (VPC) and initiates every connection from there under a Service Execution Role (SER). Those ENIs sit in private subnets that typically have no NAT or internet gateway, so each external dependency needs an explicit network path. The following diagram shows the full topology for an OAuth migration, including the two pieces that are commonly missed: STS Outbound Web Identity Federation (for the secretless grants) and the interface VPC endpoints for STS and Secrets Manager.

Deployment architecture: the source environment holds the IdP and Kafka brokers; the AWS account holds STS, Secrets Manager, and the Amazon MSK VPC, whose private subnets contain the Replicator ENIs and target cluster, reached through interface VPC endpoints.

Figure 5: Deployment architecture. The source environment holds the IdP and Kafka brokers. The AWS account holds STS, Secrets Manager, and the Amazon MSK VPC, whose private subnets contain the Replicator ENIs and target cluster, reached through interface VPC endpoints.

The source environment (on the left, shown as on-premises here, but it can equally be another cloud or a self-managed cluster on AWS) holds two components: the IdP token endpoint and JWKS (Keycloak, Okta, Entra ID) and the external Kafka brokers on a SASL_SSL / OAUTHBEARER listener. Everything else runs in your AWS account.

The two dotted lines are trust relationships you configure ahead of time, not runtime calls:

  • External Kafka validates token by using IdP JWKS – The broker checks every presented access token against the IdP’s published public keys. This applies to all grants.
  • IdP trusts STS issuer through JWKS – For the secretless grants only, the IdP is configured to trust your account’s STS issuer and validate the STS-signed JWT against STS’s JWKS. When STS Outbound Web Identity Federation is enabled, AWS provisions a per-account issuer URL (https://<id>.tokens.sts.global.api.aws) whose JWKS the IdP trusts. This trust is not used by CLIENT_CREDENTIALS.

The numbered arrows are the runtime flow, all originating from the Replicator ENIs:

  • Step 1: Fetch client credentials and the CA certificate from AWS Secrets Manager, through its VPC endpoint. For CLIENT_CREDENTIALS this includes the client_id/client_secret. For the secretless grants it is only the CA certificate(s).
  • Step 1a (optional): Call GetWebIdentityToken on AWS STS, through the STS VPC endpoint, to mint a JWT of Replicator’s AWS identity. Required only for IAM_JWT_BEARER and CLIENT_CREDENTIALS_ASSERTION.
  • Step 2: Get a signed JWT access token from the IdP token endpoint, exchanging either the client secret or the STS JWT depending on the grant.
  • Step 3: Present the token to the external Kafka brokers over SASL/OAUTHBEARER.
  • Step 4: Replicate to the target Amazon MSK cluster using IAM authentication.

The two supporting pieces inside the VPC, the Secrets Manager and STS interface VPC endpoints, are commonly overlooked precisely because the private subnets have no NAT or internet gateway. We cover exactly why they’re needed, and when, in the following section, Cross-cutting requirements.

Configuring and creating the replicator

With the architecture in mind, you can now configure Replicator itself. MSK Replicator models OAuth through a saslOAuthBearer structure on the external cluster’s clientAuthentication. Exactly one of three mechanism members must be present: clientCredentials, iamJwtBearer, or clientCredentialsAssertion. The control plane enforces this mutual exclusivity. Fields shared across all three (tokenEndpointUrl, scope, tokenEndpointAuthenticationMethod, tokenEndpointTlsCertificateArn, and saslExtensions) live at the saslOAuthBearer level.

Before the per-grant details, here are the requirements that apply to every OAuth migration, whichever grant you choose. Most OAuth setup failures trace back to one of these, so review them first.

Cross-cutting requirements

Here are the five items that apply to every grant: TLS trust, secret format, network reachability, the Service Execution Role, and STS federation.

a) TLS everywhere, and two separate trust settings

Replicator connects to two TLS endpoints, and they are configured independently:

  • encryptionInTransit.rootCaCertificate: the CA that signed your Kafka brokers’ TLS certificates (the SASL_SSL listener – :9096).
  • tokenEndpointTlsCertificateArn: the CA that signed your IdP’s token endpoint TLS certificate (for example – Keycloak on :8443).

If your broker and IdP are signed by the same private CA, you still must supply the CA in both fields. Omitting tokenEndpointTlsCertificateArn when the IdP uses a private or self-signed cert produces a PKIX path building failed error during token acquisition. Because that fails before workers stabilize, you’ll see a generic failure with no worker logs. If your IdP uses a publicly-trusted certificate (for example, it sits behind a public endpoint), you can omit tokenEndpointTlsCertificateArn entirely.

b) Secret format: store key/value pairs, not raw values

Every secret Replicator reads (client credentials, CA certificate) is parsed by the config provider as a set of key/value pairs. Use the Secrets Manager console’s Key/value editor rather than pasting raw text, and it will serialize and escape the values for you.

The keys the provider expects:

Key Value Used for
certificate the CA in PEM (newlines escaped as \n) CA-certificate secrets (rootCaCertificate, tokenEndpointTlsCertificateArn)
client_id, client_secret your OAuth client credentials the CLIENT_CREDENTIALS token-request secret

Custom parameters, headers, and SASL extensions. Some IdPs require extra data on the token request, and some brokers require SASL/OAUTHBEARER extensions. The config provider supports both through reserved key prefixes in the same secret:

Prefix Effect Example key Example value
custom_param. adds a parameter to the token request sent to the IdP custom_param.tenant_token myTenantToken
custom_header. adds an HTTP header to the IdP token request custom_header.X-Tenant-Id acme
extension. adds a SASL/OAUTHBEARER extension presented to the broker (for example, Confluent Cloud’s logicalCluster) extension.logicalCluster myLogicalClusterId

For example, an IdP that expects a tenant token as a request parameter and a Confluent Cloud broker that requires a logical-cluster extension would add custom_param.tenant_token and extension.logicalCluster as extra key/value pairs alongside client_id/client_secret in the same secret.

c) Network reachability from Replicator’s ENIs

Replicator attaches ENIs into the subnets you specify (through the target amazonMskCluster cluster’s vpcConfig) and initiates all connections from there. Those ENIs must be able to reach:

  1. Your external brokers, over VPC peering, AWS Transit Gateway, AWS Direct Connect, or VPN, with security groups permitting the SASL_SSL port.
  2. Your IdP’s token endpoint, over the same networking. The endpoint hostname must resolve from those subnets.
  3. AWS Secrets Manager, to fetch credentials/CA. If the subnets have no NAT/internet gateway, add an interface VPC endpoint for com.amazonaws.<region>.secretsmanager with private DNS.
  4. AWS STS (only for IAM_JWT_BEARER and CLIENT_CREDENTIALS_ASSERTION), to call GetWebIdentityToken. In no-egress subnets this will time out (STS GetWebIdentityToken call failed: Connect timed out) unless you add an interface VPC endpoint for com.amazonaws.<region>.sts with private DNS. This is the most common oversight for the secretless grants.

Both endpoints use private DNS, so the standard secretsmanager.<region>.amazonaws.com and sts.<region>.amazonaws.com hostnames resolve to the endpoint inside the VPC, with no client change needed.

A note on vpcConfig placement. For an external Apache Kafka cluster, vpcConfig is specified on the target amazonMskCluster entry, not the external apacheKafkaCluster entry. The API rejects a vpcConfig on the external cluster. The ENIs it creates are what reach both clusters and all AWS endpoints.

d) The Service Execution Role (SER)

Replicator assumes an IAM role to do its work. Two parts matter:

  • Trust policy – Must allow the Replicator service to assume it. kafka.amazonaws.com needs to be trusted. A trust policy that is too narrow fails with AccessDenied.ServiceExecutionRoleUnassumable.
  • Permissions – The replication permissions are extensive and depend on which features you enable, so follow the service execution role permissions reference to build a least-privilege policy.

e) Enabling STS Outbound Web Identity Federation (secretless grants only)

For IAM_JWT_BEARER and CLIENT_CREDENTIALS_ASSERTION, sts:GetWebIdentityToken must be enabled for your account/role. When enabled, AWS provisions a dedicated issuer URL of the form https://<uuid>.tokens.sts.global.api.aws. Every JWT STS mints for your account carries this as its iss claim, and its public keys are published under this issuer’s JWKS. You configure your IdP to trust this issuer. Granting the sts:GetWebIdentityToken IAM action is necessary but not sufficient. The account-level federation feature must also be turned on.

Create the replicator

A repeatable way to create the replicator is with a request file and --cli-input-json, so you can keep the full configuration under version control. The following example is a complete CLIENT_CREDENTIALS request. The two secretless variants change only the saslOAuthBearer block (shown after).

aws kafka create-replicator \
  --region <region> \
  --cli-input-json file://create-replicator.json

create-replicator.json:

{
  "replicatorName": "oauth-migration-replicator",
  "serviceExecutionRoleArn": "arn:aws:iam::<acct>:role/msk-replicator-execution-role",
  "kafkaClusters": [
    {
      "apacheKafkaCluster": {
        "apacheKafkaClusterId": "<source-cluster-id>",
        "bootstrapBrokerString": "b-1.ext-kafka.example.com:9096,b-2.ext-kafka.example.com:9096"
      },
      "clientAuthentication": {
        "saslOAuthBearer": {
          "tokenEndpointUrl": "https://idp.example.com/realms/kafka/protocol/openid-connect/token",
          "clientCredentials": {
            "tokenRequestSecretArn": "arn:aws:secretsmanager:<region>:<acct>:secret:<oauth-creds>"
          },
          "tokenEndpointAuthenticationMethod": "POST",
          "tokenEndpointTlsCertificateArn": "arn:aws:secretsmanager:<region>:<acct>:secret:<idp-ca>"
        }
      },
      "encryptionInTransit": {
        "encryptionType": "TLS",
        "rootCaCertificate": "arn:aws:secretsmanager:<region>:<acct>:secret:<broker-ca>"
      }
    },
    {
      "amazonMskCluster": {
        "mskClusterArn": "arn:aws:kafka:<region>:<acct>:cluster/target-msk/<uuid>"
      },
      "vpcConfig": {
        "subnetIds": [
          "subnet-aaaa",
          "subnet-bbbb",
          "subnet-cccc"
        ],
        "securityGroupIds": [
          "sg-xxxxxxxx"
        ]
      }
    }
  ],
  "replicationInfoList": [
    {
      "sourceKafkaClusterId": "<source-cluster-id>",
      "targetKafkaClusterArn": "arn:aws:kafka:<region>:<acct>:cluster/target-msk/<uuid>",
      "targetCompressionType": "NONE",
      "topicReplication": {
        "topicsToReplicate": [
          ".*"
        ],
        "detectAndCopyNewTopics": true,
        "copyTopicConfigurations": true
      },
      "consumerGroupReplication": {
        "consumerGroupsToReplicate": [
          ".*"
        ],
        "detectAndCopyNewConsumerGroups": true,
        "synchroniseConsumerGroupOffsets": true
      }
    }
  ]
}

Field names and exact nesting follow the create-replicator API reference. Check it for the full schema and any Region-specific values.

The example above uses CLIENT_CREDENTIALS. For the full schema, any Region-specific values, and detailed examples for the other grant types, check the MSK documentation.

With the requirements and configuration in hand, here is the order to put them in:

  1. Pick your grant type using the preceding decision table. CLIENT_CREDENTIALS is the fastest path if you already manage a client secret. Otherwise choose a secretless grant based on how your IdP models external workloads. For a multi-hop internal chain, use IAM_JWT_BEARER against the proxy pattern described in the next section.
  2. Prepare the IdP: create the client (or the STS-trust configuration), and note the exact token endpoint URL and issuer.
  3. Stage secrets in Secrets Manager, as JSON (requirement b): client credentials (if any) and the CA certificate(s).
  4. Wire the network (requirement c): connectivity from Replicator’s subnets to your brokers and IdP, plus interface VPC endpoints for Secrets Manager and (secretless grants only) STS, both with private DNS.
  5. [Optional but recommended]: Smoke-test the path from inside the VPC – IdP setup is often the part that takes the most iterations, and Replicator provisioning is a slow way to discover a misconfigured token endpoint or a missing TLS trust. Spin up a small EC2 instance in Replicator’s subnets, install a Kafka client, and run an end-to-end produce/consume against the external brokers using SASL/OAUTHBEARER (a client_credentials flow is simplest). This validates the three things most likely to be wrong (network reachability to the IdP and brokers, both TLS trusts for the broker CA and IdP CA, and token vending) while you can still fix them in seconds. Tear the instance down once the round trip works.
  6. Enable STS Outbound Web Identity Federation (requirement e. Secretless grants only) and configure your IdP to trust the resulting issuer.
  7. Build the SER (requirement d) with a trust policy the Replicator service can assume and the required permissions.
  8. Create the replicator with the create-replicator request for your grant. Remember both TLS trust fields for a private-CA IdP (requirement a), and vpcConfig on the target entry only.
  9. Verify – Produce to a topic on the external cluster and confirm the records land on the target (consume with IAM auth on the Amazon MSK side). Then watch the health signals:
    • In the Amazon MSK console, the replicator should reach the RUNNING state.
    • In Amazon CloudWatch, under the AWS/Kafka namespace, watch the replicator’s ReplicationLatency and MessageLag metrics. Both should be low and stable, and MessageLag should trend toward zero as it catches up.
    • A healthy replicator commits offsets continuously. A steady “1 message per batch” with no producer activity is only the internal heartbeat topic, not a stall.

Handling an additional identity layer: the federation-proxy pattern

Who owns what – Before the details, the ownership line is simple and worth stating up front:

  • What Replicator guarantees: it calls the configured tokenEndpointUrl with the configured grant, includes the STS JWT, expects a standard {access_token, token_type, expires_in} response, and refreshes before expiry.
  • What you own: everything at and behind the proxy, including validating the STS JWT, the downstream token exchanges, claim mapping, and the availability and latency of the endpoint. The proxy runs in your VPC and is owned entirely by you.

So far we have assumed you can point Replicator at a single token endpoint. Some organizations can’t. Instead, they have an internal identity chain: several hops of token exchange and federation that a workload must traverse before it holds a token the Kafka brokers accept.

A representative example is a large financial institution whose chain has several hops: an AWS workload’s identity (a signed GetCallerIdentity request) is exchanged at an internal Token Exchange service for an intermediate JWT, which an internal IdP then consumes as a client_assertion to issue the final Bearer token the Kafka brokers accept.

Replicator connects to a single HTTPS token endpoint using one of the three grant types and expects a standard token response. When the identity flow spans multiple hops like this, you place a proxy in front of that chain so Replicator still sees a single endpoint.

The solution: a customer-owned proxy

You deploy a small proxy in your own VPC that collapses the chain behind a single endpoint. From Replicator’s perspective, this is an ordinary OAuth flow against one token endpoint. Everything behind that endpoint is opaque to Replicator and owned entirely by you.

The grant Replicator uses to reach the proxy is a separate choice from the exchanges happening behind it. We recommend a secretless grant (IAM_JWT_BEARER or CLIENT_CREDENTIALS_ASSERTION) so there is no long-lived secret between Replicator and the proxy. CLIENT_CREDENTIALS is also valid if you would rather the proxy authenticate Replicator with a client secret. The following walkthrough uses IAM_JWT_BEARER, where the proxy validates the STS JWT that Replicator presents.

How it works, end to end. The following sequence diagram traces the full token exchange, from Replicator’s request to the Bearer it finally presents to the external Kafka brokers.

Federation-proxy token flow: the proxy validates Replicator’s STS JWT, exchanges its own AWS identity at the Token Exchange service for an intermediate JWT, presents that to the internal IdP, and returns the resulting Bearer token to Replicator.

Figure 6: Federation-proxy token flow. The proxy validates Replicator’s STS JWT, exchanges its own AWS identity at the Token Exchange service for an intermediate JWT, presents that to the internal IdP, and returns the resulting Bearer to Replicator.

  1. Replicator to proxy – Replicator POSTs its STS JWT as assertion to the proxy’s token endpoint, a plain IAM_JWT_BEARER request (grant_type=jwt-bearer). Because the endpoint is private, Replicator reaches it through an execute-api interface VPC endpoint, the same private-connectivity approach used for Secrets Manager and STS. (Replicator first obtains the STS JWT by calling STS GetWebIdentityToken through the STS VPC endpoint.)
  2. Proxy validates the STS JWT (signature against STS’s JWKS, plus iss/aud/exp/sub checks. The sub is the caller’s AWS ARN).
  3. Proxy to Token Exchange service – The proxy exchanges its own AWS identity, presented as a signed GetCallerIdentity request, at the internal Token Exchange service.
  4. Token Exchange service → proxy – It returns a signed intermediate JWT.
  5. Proxy to internal IdP – The proxy makes a client_credentials request that carries the intermediate JWT as the client_assertion.
  6. Internal IdP to proxy – The IdP issues the final Bearer access token.
  7. Proxy to Replicator – The proxy returns the Bearer, and Replicator presents it to the external brokers over SASL/OAUTHBEARER. The brokers validate it against the final IdP’s JWKS, a completely ordinary OAuth handshake from their point of view.

Reference architecture

Here is the reference architecture for the end-to-end solution.

Federation-proxy reference architecture: Replicator ENIs in a private subnet call a customer-owned proxy (a Lambda function behind a private API Gateway) that runs the on-premises identity chain over Direct Connect before Replicator replicates into the target Amazon MSK cluster.

Figure 7: Federation-proxy reference architecture. Replicator ENIs in a private subnet call a customer-owned proxy (a Lambda behind a private API Gateway), which runs the on-premises identity chain over Direct Connect before Replicator replicates into the target Amazon MSK cluster.

Everything on the Replicator side runs in your VPC’s private subnets: the Replicator ENIs, the customer-owned proxy, and the target Amazon MSK cluster. The proxy here is an AWS Lambda function behind a private Amazon API Gateway, but it can run on any compute you prefer (EC2, ECS, or EKS) as long as it exposes a single private HTTPS token endpoint. Connectivity to the on-premises Token Exchange service, internal IdP, and Kafka brokers runs over AWS Direct Connect (a VPN or VPC peering works too).

The outer legs of this flow are exactly the base migration from Solution overview: step 1 (fetch the broker CA from Secrets Manager), step 1a (mint the STS JWT through STS), step 3 (present the Bearer to the brokers), and step 4 (replicate to the target with IAM). What’s new here is the proxy hop in the middle, which replaces the single “step 2” call to a token endpoint:

  • 2. POST /token – Replicator sends the STS JWT as the assertion to the proxy’s private token endpoint, reached through the execute-api interface VPC endpoint. The proxy validates it against STS’s JWKS.
  • 2a. Exchange AWS identity – The proxy presents its own AWS identity (a signed GetCallerIdentity request) to the internal Token Exchange service and gets back a signed intermediate JWT.
  • 2b. Present as client_assertion – The proxy sends a client_credentials request to the internal IdP with the intermediate JWT as the client_assertion, and receives the final Bearer.
  • 2c. Final Bearer token – The proxy returns the Bearer to Replicator, which then continues at step 3.

As in the base architecture, the dotted lines are prerequisite trust relationships, not runtime calls: the proxy trusts AWS STS as an issuer (validating the STS JWT against STS’s JWKS), and the Kafka brokers validate the final Bearer against the internal IdP’s JWKS.

One subtlety worth calling out is the split of TLS trust. Replicator connects directly only to the private API Gateway (which uses a publicly trusted certificate) and to the Kafka brokers, so the only certificate it fetches from Secrets Manager is the broker CA. The internal IdP’s CA is the proxy’s concern: the proxy terminates TLS to the Token Exchange service and internal IdP, so it carries their CA material, not Replicator.

The same single-endpoint pattern handles other “extra layer” scenarios without any Replicator change: claim enrichment (the proxy intercepts and augments), rate-limited IdPs (the proxy caches tokens), IdPs requiring mTLS (the proxy terminates Replicator’s HTTPS and initiates mTLS onward), and IdP migrations (swap the proxy’s target without touching Replicator config).

A working reference implementation of this customer-owned proxy is available at GitHub.

Conclusion

In this post, we walked through how to migrate a self-managed, OAuth-authenticated Apache Kafka cluster to Amazon MSK using MSK Replicator: how the SASL/OAUTHBEARER handshake works, how to map your identity provider to one of the three supported grant types, the deployment architecture and prerequisites that the connection depends on, and how to handle identity providers that sit behind an additional federation layer. To get started, see the Amazon MSK Developer Guide and the Amazon MSK Replicator documentation. For the federation-proxy example, see the sample implementation on GitHub.


About the author

Subham Rakshit

Subham Rakshit

Subham is a Streaming Solutions Architect for Analytics at AWS based in the UK. He works with customers to design and build search and streaming data platforms that help them achieve their business objective. Outside of work, he enjoys spending time solving jigsaw puzzles with his daughters.

Setting up an RCS agent with an AI coding assistant and AWS End User Messaging

Post Syndicated from Bruno Giorgini original https://aws.amazon.com/blogs/messaging-and-targeting/setting-up-an-rcs-agent-with-an-ai-coding-assistant-and-aws-end-user-messaging/

Clone a repo, open it in your AI coding assistant, type “go,” and walk away with a working RCS agent.

Creating an RCS agent on AWS End User Messaging normally means juggling 23 registration fields, three different CLI parameter types, brand asset requirements, and a multi-step approval process. An AI coding assistant can handle all of that for you. With AWS End User Messaging, you can create RCS agents that send and receive rich messages complete with your brand’s logo, colors, and verified identity.

Setting up an RCS agent involves creating an agent container, uploading brand assets, configuring a 23-field registration, submitting for approval, adding verified testers, and testing both outbound and inbound messaging. Each field has a specific type (TEXT, SELECT, or ATTACHMENT) that requires a different CLI parameter, and getting any of them wrong means starting over.

We built an open-source sample repository that encodes all of this knowledge into an AGENTS.md file. When you open the repo in an AI coding assistant like Kiro, Cursor, or Windsurf, the assistant reads the instructions and walks you through the entire setup interactively. You provide a brand name and your phone number. The AI handles everything else.

How it works

The repository aws-samples/sample-rcs-agent-setup-and-send-messages contains:

  • AGENTS.md — A structured instruction file that AI coding assistants read automatically. It contains the complete RCS agent setup workflow: credential checks, brand asset generation, registration field configuration, tester management, and message testing.
  • brand-assets/ — Template SVG files for the agent logo (224×224 px) and banner (1440×448 px), ready to be customized and converted to PNG.
  • .kiro/steering/rcs-agent-setup.md — A Kiro-specific steering file with the same instructions, using the inclusion: always frontmatter so Kiro loads it automatically.

The AGENTS.md file is the key. It defines six skills that the AI assistant executes in sequence:

  1. Create RCS agent — Creates the agent container, generates brand assets (logo and banner SVGs), converts them to PNG, creates a test registration, sets all 23 fields with the correct parameter types, and submits for approval.
  2. Add verified testers — Registers test phone numbers and guides you through accepting the tester invitation.
  3. Send a test message — Checks for blockers (protect configuration, opt-out lists) and sends your first branded RCS message.
  4. Set up inbound keyword — Configures an automatic response keyword so you can test inbound messaging without writing backend code.
  5. Verify inbound messaging — Walks you through the console deep link flow to confirm two-way messaging works.
  6. Delete an RCS agent — Removes an agent cleanly by disabling deletion protection, deleting the associated registration, then deleting the agent itself.

Prerequisites

Before you start, you need:

  • An AWS account with access to AWS End User Messaging.
  • AWS Command Line Interface (AWS CLI) v2.35.12 or later installed and configured with credentials that have pinpoint-sms-voice-v2:* permissions.
  • An AI coding assistant that reads AGENTS.md files (Kiro, Cursor, Windsurf, or similar).
  • librsvg for SVG to PNG conversion (brew install librsvg on macOS).
  • A test phone that supports RCS messaging.

Getting started

Follow these steps to go from zero to a working RCS agent. The entire process takes about five minutes.

Step 1: Clone the repository

git clone https://github.com/aws-samples/sample-rcs-agent-setup-and-send-messages.git
cd sample-rcs-agent-setup-and-send-messages

Step 2: Open in your AI coding assistant

Open the cloned directory in your preferred AI coding assistant. The assistant will automatically detect the AGENTS.md file (or .kiro/steering/rcs-agent-setup.md if you are using Kiro).

Step 3: Type “go”

In the chat panel, type go. The AI assistant will:

  1. Check your AWS credentials — It runs aws sts get-caller-identity and asks how you authenticate if credentials are not configured. It supports named profiles, SSO, IAM user credentials, and environment variables.
  2. Verify EUM access — It confirms your account can use AWS End User Messaging.
  3. Check tooling — It verifies rsvg-convert is installed for brand asset generation.
  4. Ask for your preference — Quick mode (provide a brand name) or interactive mode (you specify every detail).

Step 4: Provide a brand name

In quick mode, you provide a brand name and the AI generates everything else: a description, an accessible accent color, contact information with placeholder values, privacy and terms URLs, and custom SVG brand assets with your brand name and colors.

In interactive mode, the AI asks for each detail one section at a time: brand name, accent color, logo description, banner description, contact information, and policy URLs.

Step 5: Watch it work

The AI assistant executes every AWS CLI command in sequence:

  1. Creates the RCS agent container.
  2. Enables deletion protection.
  3. Creates a test registration and links it to the agent.
  4. Generates and converts brand asset SVGs to PNG.
  5. Uploads the logo and banner as registration attachments.
  6. Sets all 23 registration fields using the correct parameter type for each (TEXT, SELECT, or ATTACHMENT).
  7. Submits the registration and polls for approval.
  8. Reports when the agent is active.

Step 6: Add a tester and send a message

Once the agent is approved, the AI asks for your test phone number, registers it as a verified tester, and waits for you to accept the invitation. After verification, it checks for blockers (protect configuration and opt-out lists), then sends your first branded RCS message.

Step 7: Test inbound messaging

The AI configures an automatic keyword response and walks you through the console deep link flow to verify two-way messaging. When you send RCSINBOUNDTESTING to your agent, you receive an automatic reply confirming inbound messaging works.

What the AI handles for you

The AGENTS.md file encodes several non-obvious behaviors that would otherwise require trial and error:

Challenge How the repo handles it
create-rcs-agent takes no --display-name parameter The brand name comes from the registration, not the agent creation call. The instructions reflect this.
Three different field parameter types The instructions include a field reference table mapping each of the 23 fields to its correct CLI parameter: --text-value, --select-choices, or --registration-attachment-id.
--field-values does not exist The instructions explicitly warn against this non-existent parameter and use the correct alternatives.
--attachment-body and --attachment-url conflict The instructions use --attachment-body only.
Accent color contrast requirements The instructions include pre-validated color choices with 4.5:1 contrast ratio against white.
Field paths differ from what you might expect The correct paths are agentDetails.logoImage and agentDetails.bannerImage, not logoAttachmentId or bannerAttachmentId.
New registration versions do not inherit field values The troubleshooting section warns that all 23 fields must be re-populated when creating a new version.

Customizing the repo

You can modify the AGENTS.md file to fit your workflow:

  • Change default values — Update placeholder contact information, privacy URLs, or terms URLs to match your organization.
  • Add custom brand assets — Replace the template SVGs in brand-assets/ with your own designs. Keep the logo at 224×224 px and the banner at 1440×448 px.
  • Extend the skills — Add new skills for richer message types (cards, carousels), event destinations for programmatic inbound handling, or integration with other AWS services.

Cleanup

To remove the resources created during testing:

# 1. Disable deletion protection
aws pinpoint-sms-voice-v2 update-rcs-agent \
  --rcs-agent-id <your-agent-id> \
  --no-deletion-protection-enabled \
  --region us-east-1

# 2. Delete the associated registration (required before deleting the agent)
aws pinpoint-sms-voice-v2 delete-registration \
  --registration-id <your-registration-id> \
  --region us-east-1

# 3. Delete the agent
aws pinpoint-sms-voice-v2 delete-rcs-agent \
  --rcs-agent-id <your-agent-id> \
  --region us-east-1

Note: You must delete the registration before the agent. Skipping this step results in a ConflictException: RESOURCE_NOT_EMPTY error.

Conclusion

The aws-samples/sample-rcs-agent-setup-and-send-messages repository turns a multi-step, error-prone CLI workflow into a guided conversation. Clone the repo, open it in your AI coding assistant, type “go,” and you have a working RCS agent that can send and receive branded messages to verified testers.

The AGENTS.md pattern is reusable. Any complex AWS workflow with non-obvious API behavior can be encoded the same way: document the correct commands, parameter types, and pitfalls in a structured file, and let the AI assistant execute it interactively.

For a detailed manual walkthrough of the same process, see Creating and testing an RCS agent with AWS End User Messaging. For an overview of the business case for RCS, see Upgrade business messaging with RCS on AWS. For more information, see the AWS End User Messaging service page and the RCS documentation.


About the author

Secure SageMaker Unified Studio access with SAML and conditional policies

Post Syndicated from Manos Samatas original https://aws.amazon.com/blogs/big-data/secure-sagemaker-unified-studio-access-with-saml-and-conditional-policies/

Amazon SageMaker Unified Studio is a single data and AI development environment that brings together data preparation, analytics, and machine learning (ML) development in one place. By unifying these workflows, it saves teams from managing multiple tools and makes it straightforward for data scientists, analysts, and developers to build, train, and deploy ML models while collaborating. In Amazon SageMaker Unified Studio, a domain is the organizing entity for connecting your assets, users, and their projects. With Amazon SageMaker unified domains, you have the flexibility to reflect the data and analytics needs of your organizational structure. You can create a single unified domain for your enterprise or multiple domains for different business units.

Some enterprises, especially those in regulated industries, might require limiting access to trusted networks (such as VPN CIDRs) or to managed devices that meet compliance standards through device attestation.

In this post, we demonstrate how to integrate SageMaker Unified Studio as a custom SAML application and apply conditional access policies for enforcing device compliance, IP-based restrictions, or multi-factor authentication (MFA). For this post, we use Okta as the identity provider (IdP).

Solution overview

This solution demonstrates how to integrate Amazon SageMaker Unified Studio (SMUS) with external SAML identity providers such as Okta. The integration enforces enterprise security controls, including trusted network access, device compliance, and multi-factor authentication. With this integration, organizations in regulated industries can maintain strict access controls while providing single sign-on for their data science and AI development teams. By using SAML 2.0 federation with conditional access policies, you can help make sure that only authenticated users on compliant devices from trusted networks gain access. This access applies to your SageMaker Unified Studio domains and the associated data and AI workloads.

SAML authentication flow from a corporate device through the identity provider and AWS STS to Amazon SageMaker Unified Studio

Authentication flow for accessing SageMaker Unified Studio through SAML

The architecture diagram illustrates the secure authentication flow for accessing SageMaker Unified Studio through SAML integration:

  1. Users typically initiate access from corporate-managed devices through VPN or trusted network connections.
  2. The IdP authenticates the user and evaluates conditional access policies defined by your organization. Based on these policies, it checks for trusted devices, approved source IP ranges, and MFA completion. If any policy fails, the login is rejected. Otherwise, authentication proceeds.
  3. Upon successful authentication and policy validation, the IdP generates a digitally signed SAML assertion containing user attributes and group memberships, securely delivering it to the user’s browser through HTTP POST binding.
  4. The client browser automatically posts the SAML assertion to the AWS Security Token Service (AWS STS) sign-in endpoint. There, the AWS IAM Identity Provider validates the trust relationship with your corporate IdP through pre-configured SAML federation settings.
  5. AWS STS validates the SAML assertion signature and authenticity. It then maps the user attributes to a specifically configured IAM role with SageMaker Unified Studio permissions, including the datazone:GetIamPortalLoginUrl permission required for domain access.
  6. AWS STS confirms successful role assumption and generates temporary AWS credentials with a defined session duration. It then issues an HTTP redirect that returns the browser to the SageMaker Unified Studio domain with authenticated session tokens.
  7. Users gain access to the unified environment for data preparation, analytics, and machine learning development. All activities are governed by the assumed IAM role permissions and logged for comprehensive audit trails.

Walkthrough

In this walkthrough, you create a SAML application in Okta, connect it to AWS, and configure a SageMaker Unified Studio domain to use it for authentication.

Prerequisites

Before you get started, make sure you have the following:

  1. Familiarity with Amazon SageMaker Unified Studio.
  2. A basic understanding of SAML 2.0.
  3. AWS Identity and Access Management (IAM) permissions to create a domain in Amazon SageMaker Unified Studio.
  4. Access to your SAML IdP (such as Okta or Entra ID) to create and configure a SAML application.

Step 1: Create an application in Okta

The first step is to set up a new SAML application in Okta that manages authentication for SMUS.

  1. In Okta, go to Applications → Create App Integration, and choose SAML 2.0.
  2. Provide an App name.
  3. Set the Single sign-on URL to https://signin.aws.amazon.com/saml.
  4. Set Name ID format to Persistent.
  5. Set the Audience URI (SP Entity ID) to https://signin.aws.amazon.com/saml.
  6. Choose Next, and finish creating the application.
  7. Once created, copy the Metadata URL and Sign On URL. You need these in later steps.

Step 2: Create an identity provider in IAM

Now, let’s connect Okta to AWS by creating an IAM identity provider. This allows AWS to trust authentication responses from Okta.

  1. Open the IAM console.
  2. Go to Identity providers → Add provider.
  3. Select SAML as the provider type.
  4. Provide a Provider name.
  5. In Okta, go to your application’s Sign On tab, choose Identity Provider metadata, and save the XML file. Upload it here.
  6. Choose Add provider.
  7. Copy the ARN of this provider. You need it when you create the role.

Step 3: Create an IAM role for Okta

Next, create an IAM role that Okta can assume. This role defines what access users have when they sign in through Okta.

  1. In IAM, go to Roles → Create role.
  2. Use the following trust policy (replace both instances of “{Replace with Identity provider ARN}” with the ARN you copied in Step 2):
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Effect": "Allow",
            "Principal": {
                "Federated": "{Replace with Identity provider ARN}"
            },
            "Action": "sts:AssumeRoleWithSAML",
            "Condition": {
                "StringEquals": {
                    "SAML:aud": "https://signin.aws.amazon.com/saml"
                }
            }
        },
        {
            "Effect": "Allow",
            "Principal": {
                "Federated": "{Replace with Identity provider ARN}"
            },
            "Action": "sts:TagSession",
            "Condition": {
                "StringLike": {
                    "aws:RequestTag/Email": "*"
                }
            }
        }
    ]
}
  1. Attach a permission policy. For example:
{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "VisualEditor0",
            "Effect": "Allow",
            "Action": "datazone:GetIamPortalLoginUrl",
            "Resource": "arn:aws:datazone:<REGION>:<ACCOUNT-ID>:domain/<DOMAIN-ID>"
        }
    ]
}

Replace <REGION>, <ACCOUNT-ID>, and <DOMAIN-ID> with the corresponding values from your SageMaker Unified Studio domain ARN (arn:aws:sagemaker:<REGION>:<ACCOUNT-ID>:domain/<DOMAIN-ID>). You can find the domain ARN in the SageMaker console under Domains.

Step 4: Configure SAML assertions

To make sure AWS understands who is signing in, configure the SAML assertions in Okta.

  1. Open your application in Okta.
  2. Go to General → SAML Settings → Edit.
  3. Choose Next until you reach Attribute Statements.
  4. Add the following mappings:
    • https://aws.amazon.com/SAML/Attributes/PrincipalTag:Email → user.email.
    • https://aws.amazon.com/SAML/Attributes/Role → {IAMROLEARN,IdentityProviderARN}.
    • https://aws.amazon.com/SAML/Attributes/RoleSessionName → user.email.

Step 5: Create an SMUS domain

Finally, let’s set up the SMUS domain and tie it all together.

Note: Creating a SageMaker Unified Studio domain incurs charges. For pricing details, see the Amazon SageMaker pricing page.

  1. Open the Amazon SageMaker console.
  2. Choose Create domain.
  3. Choose Manual setup (this allows for SAML integration).
  4. Enter a domain name, then choose Create.
  5. In Configure SSO user access, select SAML, then choose Next.
  6. Set the IdP SSO URL to the Sign On URL from Step 1.
  7. Select Do not require assignments. (Access is instead managed by your IdP team through Okta or Entra.)
  8. Choose Next, then choose Save.

To verify the integration works, open your SMUS domain and choose Sign in with SSO. You are redirected to Okta, and conditional access policies such as VPN, device attestation, or MFA apply automatically.

  1. Open your SMUS domain URL in a browser.
  2. Choose Sign in with SSO.
  3. Confirm that you are redirected to Okta for authentication.
  4. Sign in with your Okta credentials.
  5. Verify that you are redirected back to the SMUS domain with access to your projects.

Step 6: Assign users to the Okta application

Before users can authenticate through Okta to access SMUS, you must assign them to the application.

  1. In Okta, navigate to your SAML application.
  2. Go to the Assignments tab.
  3. Choose Assign, and select Assign to People or Assign to Groups.
  4. Select the users or groups who need access to SMUS.
  5. Choose Save and Go Back, then choose Done.

Step 7: Apply conditional access policies

Up to Step 5, we configured SMUS with an external SAML IdP. At this point, anyone assigned to the new application in your IdP can sign in and access the SMUS domain.

This is where conditional access policies come into play. Based on your organization’s governance model, you can add policies in your IdP to further control how and when users gain access. For example:

  • Restricting access to specific corporate IP address ranges (for example, only through VPN).
  • Enforcing device compliance so that only managed or secure devices can connect.
  • Adding MFA requirements for sensitive actions.
  • Applying device attestation to help assess whether the endpoint conforms to security baselines.

Most major IdPs, including Okta and Entra ID, support conditional access. You can find more details in their documentation:

These policies allow you to enforce the right level of protection, from something as simple as requiring users to connect through corporate networks to something as advanced as verifying device attestation across your fleet.

Clean up

To avoid incurring ongoing charges, delete the resources you created during this walkthrough:

  1. Delete the Amazon SageMaker Unified Studio domain from the SageMaker console.
  2. Delete the IAM role you created for Okta.
  3. Delete the IAM identity provider.
  4. Delete the SAML application in Okta.

Important: Deleting the SMUS domain permanently removes all projects, assets, and data within it. Back up any important work before proceeding.

Conclusion

By integrating SMUS with an external IdP through SAML, you can help enforce modern access controls based on your organization’s security requirements. This post walked through how to configure SMUS with a custom SAML application and pointed you toward resources for setting up conditional access policies.

With conditional access in place, you can decide, based on your organization’s needs, whether access should be limited to trusted users on trusted networks, trusted devices, or both. This approach can help provide a more secure and compliant login experience that aligns SMUS access with your company’s broader identity and security strategy.


About the authors

Amit Samal

Amit Samal

Amit is a Sr. Delivery Consultant in World Wide Public Sector, Professional Services at AWS working with UKGI Customers. Amit has been with AWS for about 4 years and has been helping customers across the UKGI to design & implement secure, resilient and cost-effective workloads on AWS. Amit is passionate about all areas of technology, but has focus areas in Networking, Migrations, and Application Modernizations.

Manos Samatas

Manos Samatas

Manos is a Principal Solutions Architect in Data and AI with Amazon Web Services. He works with government, non-profit, education and healthcare customers in the UK on data and AI projects, helping build solutions using AWS. Manos lives and works in London. In his spare time, he enjoys reading, watching sports, playing video games and socialising with friends.

Amazon MSK simplifies configuring custom domain names

Post Syndicated from Ali Alemi original https://aws.amazon.com/blogs/big-data/amazon-msk-simplifies-configuring-custom-domain-names/

Previously, you had to manually override the advertised listener on each broker and repeat it every time a broker was added. This approach was operationally heavy and could not be implemented on a cluster in KRaft mode. With Amazon Managed Streaming for Apache Kafka (Amazon MSK), you can now configure custom domain names for your Provisioned clusters using a single property. This works for clusters in both ZooKeeper and KRaft mode. Now you define the domain once and Amazon MSK applies it across every broker, so custom domain names keep working through scaling of the MSK cluster.

Custom domain names on Amazon MSK

Amazon MSK is a fully managed service for building and running applications that use Apache Kafka to process streaming data. By default, Amazon MSK brokers advertise addresses that AWS generates (for example, b-1.cluster-name.kafka.us-east-1.amazonaws.com) to connecting clients. These addresses are unique to each cluster and change when a cluster is recreated.

Many organizations need a static, customer-controlled endpoint that stays the same regardless of the underlying cluster. They achieve this with a custom domain name, so that they can:

  • Route traffic through Network Load Balancers (NLBs) when IP exhaustion forces clusters into non-routable subnets.
  • Avoid client reconfiguration during cluster migrations, so clients keep the same endpoint even when the underlying cluster changes.
  • Simplify disaster recovery (DR) failover, where the same domain fronts both primary and standby clusters.
  • Align with organizational naming, security, and compliance conventions.

Until now, the only way to do this was to override the advertised.listeners on each broker using the kafka-configs.sh --alter tool. It required carefully preserving every internal listener and re-running that override every time a broker was added. This works, but it accepts any string with no validation. A single typo can cause an outage. It requires manual, per-broker steps with no cluster-wide mechanism. It cannot be managed through infrastructure as code, and it could not be implemented on Amazon MSK brokers in KRaft mode. This blocked customers who rely on custom domain names from using them on KRaft-based clusters. With this launch, a single configuration property replaces all of that.

What you set up, and what Amazon MSK manages

A working custom domain name has two parts, and understanding this split up front helps the rest of this post make sense. You own the client connectivity and trust layer. Amazon MSK owns the cluster-side advertised listener configuration. The following diagram shows the client connectivity and trust layer.

Diagram of the client connectivity and trust layer you manage and the advertised listener configuration Amazon MSK manages

Figure 1: The client connectivity and trust layer (left) is a prerequisite you own and manage. The advertised listener configuration on the cluster (right) is what Amazon MSK manages for you

Important: When you apply custom.advertised.listeners, your custom domain name replaces the default addresses that clients use to connect to broker nodes. If the networking and trust layer is not already in place, resolvable, reachable, and trusted from the client, the client cannot reconnect, even though it was connected moments earlier.

Part 1: The client connectivity and trust layer (you manage)

The Prerequisites section below shows the key requirements. You can find the detailed setup in an existing post, Configure a custom domain name for your Amazon MSK cluster, which includes a diagrammed walkthrough of the NLB, Amazon Route 53, and AWS Certificate Manager (ACM) topology.

Part 2: The advertised listener configuration (Amazon MSK managed)

After the connectivity layer exists, you tell the brokers which custom address to advertise to clients. This is the part that used to require a per-broker CLI override, and it is what this launch simplifies. This next section describes how it works.

Prerequisites

Before a client can reach your brokers through a custom domain, the connectivity and trust path must exist. You create and manage this layer. It covers three things:

  • Networking: A network gateway, like a Network Load Balancer (NLB), TLS certificate, DNS records, and security groups that route traffic from your custom domain to your broker IPs.
  • Certificate trust: The client’s truststore must include certificate authorities in the path (the load balancer’s custom-domain cert).
  • DNS resolution: Clients must resolve the custom domain to your NLB, typically through an Amazon Route 53 private hosted zone associated with the client virtual private cloud (VPC).

This layer must be in place for custom domain names to function. It is a prerequisite for this feature to work.

How it works

You add a property to your Amazon MSK configuration. The value takes the form:

custom.advertised.listeners=<LISTENER>://<hostname>:<port>

where <LISTENER> is one of your cluster’s client listeners and <hostname>:<port> is the custom address pattern. For example, on an IAM cluster:

custom.advertised.listeners=CLIENT_IAM://b-{broker_id}.example.com:9000+{broker_id}

The property specifies two things:

  1. Each listener corresponds to an authentication type on your cluster. Custom advertised endpoints can be set only for client listeners: CLIENT, CLIENT_SECURE, CLIENT_SECURE_PUBLIC, CLIENT_SASL_SCRAM, CLIENT_SASL_SCRAM_PUBLIC, CLIENT_IAM, and CLIENT_IAM_PUBLIC. Internal listeners (REPLICATION, CONTROLLER) are not supported and are rejected at validation. The listener you specify must also be bound (active) on your cluster. For example, if your cluster uses only IAM authentication, specifying CLIENT_SECURE is rejected, and the error message lists the valid client listeners for your cluster.
  2. A custom hostname:port pattern that includes the {broker_id} template variable. Each broker resolves to a unique address. In this pattern, the {broker_id} template variable is replaced with each broker’s numeric ID. The port number 9000+{broker_id} means the broker ID is added to the base port 9000, so broker 1 resolves to 9001, broker 2 to 9002, broker 10 to 9010, and so on. The base port 9000 is only an example. You can use any base port, as long as the resulting ports match the TLS listeners you provisioned on your NLB.

{broker_id} can appear in the hostname, the port, or both, as long as each broker’s resolved host:port is unique. Placing it in the port alone is valid, so a shared hostname with a per-broker port also works:

custom.advertised.listeners=CLIENT_IAM://example.com:9000+{broker_id}

Before you begin, you need an MSK configuration to hold this property. You create one with the CreateConfiguration API (or the AWS Management Console), passing your server properties as the configuration body. MSK returns a configuration ARN and a revision number, which together identify the exact configuration you apply to the cluster.

custom.advertised.listeners does not need its own standalone configuration. You can include it alongside any other broker-level properties MSK already supports, such as auto.create.topics.enable, num.partitions, or log-retention settings, within a single configuration revision. If you already manage an MSK configuration for your cluster, add custom.advertised.listeners to it and create a new revision using the UpdateConfiguration API. No separate configuration is needed.

You then apply the configuration to your cluster with the UpdateClusterConfiguration API. Amazon MSK then performs three actions:

  • Validates the configuration.
  • Resolves the pattern for each broker.
  • Applies it through a rolling restart across the cluster.

These safeguards prevent you from accidentally removing or modifying the internal listeners that Amazon MSK manages. Validation is synchronous. The listener must be a client-facing listener, the pattern must include {broker_id}, and each broker’s resolved host:port must be unique. If any check fails, the API returns a descriptive error and makes no change.

The override affects only the advertised address of the named listener. Replication, authentication, multi-VPC (CLIENT_IAM_VPCE), and AWS PrivateLink connectivity remain unaffected. The change is also fully reversible: remove the custom.advertised.listeners property and re-apply the configuration, and Amazon MSK reverts the listener to its original address.

You can track progress with the DescribeOperation API, which shows state transitions from UPDATE_IN_PROGRESS to UPDATE_COMPLETE or UPDATE_FAILED. If a broker fails to start, the rollout halts at that broker, the remaining brokers keep their previous configuration, and you can fix the property and re-apply to recover.

Setting up a custom domain name end to end

When you apply custom.advertised.listeners, your custom domain name replaces the default addresses that clients use to connect to broker nodes. If the networking and trust layer is not already in place, resolvable, reachable, and trusted from the client, the client cannot reconnect, even though it was connected moments earlier.

The networking layer, the Network Load Balancer (NLB), DNS, and TLS certificate that route traffic from your custom domain to your broker IPs, is a prerequisite you own. It is not specific to this launch. The existing post Configure a custom domain name for your Amazon MSK cluster covers it in detail, with a diagrammed walkthrough of the NLB, Route 53, and ACM topology. With the networking in place, the following steps cover the cluster-side setup this launch introduces.

Step 1: Add the custom domain to your Amazon MSK configuration

Create or update an Amazon MSK configuration that includes the custom.advertised.listeners property, matching the hostnames and ports you provisioned on the NLB. For a three-broker IAM cluster fronted by an NLB with ports 9001–9003, put the property in a file:

custom.advertised.listeners=CLIENT_IAM://b-{broker_id}.example.com:9000+{broker_id}

Then create the configuration, passing the file as the server properties:

aws kafka create-configuration \
    --name "custom-domain-iam" \
    --description "Custom advertised listeners for CLIENT_IAM" \
    --server-properties fileb://custom-domain-config.txt

Use fileb:// (not file://) so the CLI reads the file as bytes and base64-encodes it. Passing the value inline is fragile because of the {broker_id} braces. Leave {broker_id} literal in the file. Amazon MSK resolves it per broker at apply time. The response returns the configuration ARN and LatestRevision.Revision, which you use in the next step.

Step 2: Apply the configuration

Apply the configuration to your cluster with UpdateClusterConfiguration, using the console, AWS Command Line Interface (AWS CLI), AWS CloudFormation, CDK, or Terraform. This is the same workflow you already use for broker configuration changes.

aws kafka update-cluster-configuration \
    --cluster-arn <your-cluster-arn> \
    --configuration-info arn=<configuration-arn>,revision=<revision> \
    --current-version <current-cluster-version>

If the configuration fails to apply, review the errors. For details, see the troubleshooting section in the Amazon MSK Developer Guide.

Step 3: Track the rollout

aws kafka describe-cluster-operation-v2 \
    --cluster-operation-arn <operation-arn>

After the configuration is accepted, Amazon MSK applies it through a rolling restart. Wait until the operation reports SUCCESS. If it reports FAILED, a broker could not apply the change. The rollout halts at that broker, the remaining brokers keep their previous configuration, and you can fix the configuration and re-apply to recover.

Step 4: Verify

Confirm clients can connect through the custom domain:

kafka-topics.sh --list --bootstrap-server b-1.example.com:9001

If your topic list is returned, clients are successfully connecting through your custom domain. If the operation reported SUCCESS but clients cannot connect, the cluster-side configuration is correct, but your networking layer likely needs attention.

Client connectivity during rollout

This step is important. Clients can be disconnected if the networking is not ready. Kafka clients do not keep using the original address they bootstrapped with. On a periodic metadata refresh, each client learns the broker’s advertised listener. The client uses that address for all subsequent connections. When you apply a custom domain name, that advertised address changes from the default name that Amazon MSK generates to your custom domain, so at the next metadata refresh every client connects over the custom domain. For this reason, the connectivity and trust layer described in What you set up, and what Amazon MSK manages is a prerequisite, not a follow-up task.

The safe sequence, which is also how customers move from Amazon DNS to a custom domain today, is two phases:

  1. Build the networking path first: Stand up the NLB, DNS, and certificate, and point your clients at the custom bootstrap endpoint, but do not set the advertised listener yet. Clients bootstrap through the custom endpoint while still connecting to brokers over the addresses that Amazon MSK generates.
  2. Configure the advertised listener: With the path already in place, applying custom.advertised.listeners changes what the brokers advertise. At the next metadata refresh, clients pick up the custom domain and cut over to it automatically.

Because the path already exists, this cutover is transparent: as Amazon MSK applies the change broker by broker, clients reconnect on their own, with no restart or reconfiguration.

Scaling and replacement of brokers

When you scale the cluster or a broker is replaced during automated healing, Amazon MSK automatically applies the configuration to the new broker, resolving {broker_id} for its ID, with no manual steps required on the cluster side. Remember to add the corresponding NLB listener, target group, and DNS record for any new broker, because the networking layer does not auto-scale.

Conclusion

Custom domain name configuration turns a per-broker CLI workaround into a single, validated, cluster-wide Amazon MSK configuration property. It works identically on ZooKeeper and KRaft, persists through scaling and failover, and flows through your existing Terraform, CloudFormation, and CLI workflows. If you rely on custom domain names, we recommend adopting the static configuration now.

This capability is available on all Amazon MSK Provisioned clusters with Standard and Express brokers, in all AWS Regions where Amazon MSK Provisioned is available. To get started, see the Amazon MSK Developer Guide and the end-to-end networking walkthrough in Configure a custom domain name for your Amazon MSK cluster.


About the authors

Ali Alemi

Ali Alemi

Ali is a Streaming Specialist Solutions Architect at AWS. Ali advises AWS customers with architectural best practices and helps them design real-time analytics data systems. Prior to joining AWS, Ali supported several public sector customers and AWS consulting partners in their application modernization journey and migration to the cloud.

Subham Rakshit

Subham Rakshit

Subham is a Streaming Specialist Solutions Architect for Analytics at AWS based in the UK. He works with customers to design and build search and streaming data platforms that help them achieve their business objective. Outside of work, he enjoys spending time solving jigsaw puzzles with his daughter.

Scaling patterns for self-organizing multi-agent clusters with Kiro

Post Syndicated from Ivo Kammerath original https://aws.amazon.com/blogs/architecture/scaling-patterns-for-self-organizing-multi-agent-clusters-with-kiro/

Most multi-agent systems today follow the same shape: a supervisor agent breaks a task down, hands the pieces to subagents, and stitches the results back together. This is how Kiro CLI delegates to subagents, and what the Strands Agents SDK gives you primitives for with graphs and agents-as-tools. It is a good default. One process holds the plan, so behavior stays predictable and every result passes through a single gate.

That one process is also the limit. Every assignment and every result flows through the supervisor, so its context window caps how much work the system can hold at once. If it dies, the run dies with it. And because a single planner fixes the decomposition upfront, you get one take on the problem, multiplied by N workers.

Plenty of distributed systems still coordinate centrally, and should. But the alternative has been around for decades: let participants converge through shared state instead. We wanted to know what happens when you apply that move to artificial intelligence (AI) agents, so we built kiro-flock, an open-source reference implementation. It runs clusters of Kiro CLI agents on Amazon Elastic Compute Cloud (Amazon EC2) with nothing between them but an Amazon Simple Storage Service (Amazon S3) bucket. No orchestrator, no message bus. Agents coordinate by reading each other’s append-only logs. This post explains the pattern and gives you enough to deploy the sample and watch a cluster converge yourself.

When to use this pattern

Architecture has to match the task. In the 2025 study “Towards a Science of Scaling Agent Systems” of 260 agent-system configurations they found exactly that: task performance ran from +80.8 percent on decomposable financial
reasoning to -70.0 percent on sequential planning, against a single-agent baseline.
Neither the supervisor nor this pattern wins everywhere.

A self-organizing cluster fits work that splits into many quasi-independent contributions toward one goal: reviewing a large code base, migrating hundreds of modules against a known target, generating tests or design alternatives at scale. It also suits brainstorming where you want real variety instead of one planner’s take. Parallelism matters more than ordering. Agents can join, fail, and leave without ceremony.

A supervisor fits the opposite profile. The task tree is known upfront, steps depend on each other, or you need a verification gate before results ship. The same study found that architectures without centralized verification propagate more errors. That is a real cost of removing the arbiter, though you can still gate the finished result the way the migration example ends in a full test pass. What a cluster will not give you is a gate between every step, and if you need that, the supervisor earns its bottleneck.

Workload profile Better fit
Many independent contributions, one goal Cluster
Decomposition should emerge from the work Cluster
Diversity of approaches is an asset Cluster
Long-running, agents come and go Cluster
Known task tree, strict ordering Supervisor
Central verification gate required Supervisor
Interactive, latency-sensitive Supervisor

The pattern

The core decision: coordination lives in shared state. No component plans, assigns, or aggregates for the rest. Three parts make it work:

  • Agents. Independent processes that read and write a shared store and never connect to each other. One agent failing stops only its own log.
  • A shared environment. A single store holds a direction file, one append-only log per agent, and a working area for artifacts.
  • A direction. A markdown file that states the goal and leaves the path to the agents.

Each agent runs a loop. It starts a fresh session, reads the direction and the logs of a bounded set of peers, decides on one contribution that moves the goal forward, writes its artifacts, and appends one line to its own log:

{"ts":"2026-07-21T14:12:42Z","iteration":0,"action":"wrote discussion on coordination topologies","result":"Created discussion-coordination-topologies.md covering ring vs mesh vs swarm trade-offs with analysis of convergence/diversity tension.","next_intent":"read neighbour contributions and either deepen topology discussion or explore a second angle"}

That line is the entire coordination message. No broker delivers it, no acknowledgment comes back. The next agent that reads it decides for itself what to do about it. Remove an agent and its neighbors read one fewer log. Add one mid-run and it joins the division of labor already underway.

The bounded peer set is deliberate. Agents sit in a logical ring and each reads a fixed number of neighbors on either side, set by a radius parameter. Give every agent full visibility and the cluster collapses onto whatever the first agent wrote, because each later agent reads that as consensus. Limited visibility lets signals spread gradually, and agents working from different context get room to develop alternatives.

In kiro-flock, each agent is a headless Kiro CLI session on its own Amazon EC2 instance, and the shared environment is an Amazon S3 bucket. Which tools an agent may use without review, and what each iteration reads and writes, are design decisions you make once per cluster. We think of them as harness engineering and loop engineering, and the drift failure mode in the following section shows why the fresh session per iteration matters.

What a run looks like

Reference architecture: EC2 agent instances, an S3 shared environment holding the direction, logs, and artifacts, an API Gateway and Lambda control plane behind Amazon Cognito, CloudWatch metrics, and Amazon Bedrock post-run analysis.

Figure 1. Reference architecture for a kiro-flock cluster on AWS.

Agents run as headless Kiro CLI sessions on EC2 instances, each reading and writing the S3 bucket that holds the direction, one log per agent, and the shared artifacts. An Amazon API Gateway and AWS Lambda control plane behind Amazon Cognito starts, stops, and steers clusters from the dashboard. Agents publish metrics to Amazon CloudWatch, and Amazon Bedrock backs the post-run analysis.

Take a concrete run: sixteen agents in a ring, directed to hold a distributed discussion on AI agent clustering and converge on a shared synthesis. The operator writes one direction file and starts the cluster. Nothing else is assigned.

The following lines are from that run (result fields shortened for print). In the first iteration the agents fanned out with no assignment: failure modes, coordination topologies, distributed-systems parallels, and several overlapping stigmergy pieces, all written in parallel within one minute of start. The later lines show an agent correcting course after reading its neighbors, the synthesis forming, and the cluster winding itself down:

{"ts":"2026-07-21T14:12:42Z","iteration":0,"action":"wrote discussion-failure-modes.md","result":"covered 5 failure modes (premature convergence, echo chambers, hot-spot collapse, idle cascades, stale reads) with mitigations","next_intent":"read neighbours next iteration, look for topics to challenge or extend"}
{"ts":"2026-07-21T14:14:31Z","iteration":1,"action":"wrote discussion-scaling-laws.md","result":"explored scaling regimes and communication cost vs value; diverged from neighbours who all wrote stigmergy in iteration 0","next_intent":"read neighbour updates, check if any uncovered angles remain"}
{"ts":"2026-07-21T14:16:04Z","iteration":2,"action":"wrote synthesis.md","result":"structured synthesis: 5 core claims, 3 key tensions, 5 open questions; integrated topologies, scaling, economics, failure modes","next_intent":"read neighbours' reactions to synthesis, refine, move toward idle if coverage is solid"}
{"ts":"2026-07-21T14:22:24Z","iteration":7,"action":"idle","result":"All 6 visible neighbours idle (iterations 4-6). Synthesis.md stable and comprehensive. Direction unchanged. Cluster fully converged.","next_intent":"remain idle unless direction changes or operator requests further work"}

The cluster converged on a shared synthesis covering the angles in the direction, and by iteration 7 all sixteen agents had declared themselves idle. Nobody assigned the topics, arbitrated the synthesis, or told the cluster it was done. Even done is only a signal read from the logs, since an agent goes idle when its neighbors are idle and the output is stable.

kiro-flock dashboard showing a single six-agent cluster running the amorphous algorithm at radius 1, each agent card listing its neighbors, health, and iteration log, with the shared environment and direction on the right.

Figure 2. A single cluster in the kiro-flock dashboard. Six agents run at radius 1, each on its own EC2 instance. Every agent card shows its neighbors and its latest log line, the “did / result / next intent” message its neighbors read. The right panel shows the shared environment in S3 and the direction the cluster works toward.

Three ways to answer “whose work do I read?”

Every iteration starts with that question, and the answer defines the coordination algorithm. kiro-flock ships three, swappable at runtime.

Amorphous (ring). Each agent reads a fixed window of neighbors set by radius R. An agent at radius 2 reads four neighbors whether the cluster holds 8 agents or 800, so per-agent work stays constant as the cluster grows. The ceiling is your EC2 vCPU quota, not the algorithm. The largest system we have run so far totaled 184 agents across 11 cooperating clusters, creating a programming language. Rings beyond the low hundreds are extrapolation from that constant per-agent cost, not tested territory. The price is speed: a signal moves one hop per iteration. That slowness is also what lets dissenting agents mature alternatives before the neighborhood locks in. Use it for parallel work, or as the opening phase before consensus.

Mesh (full visibility). Every agent reads every other agent’s latest entry. Alignment is fast and context grows linearly with the cluster, so mesh stays comfortable to about 30 agents and workable to about 50. Diversity collapses, because agents reacting to the same first signal agree instead of exploring. Use it when a small group must converge quickly.

Swarm (recency). Each agent reads the K most recently active peers, so the cluster reorganizes around where the action is. Good for ideation, runs well past 100 agents. If K stays small while N grows, most agents read the same few peers and pile onto one subtask. Raise K or switch to amorphous.

A productive sequence uses all three: open amorphous to explore, switch to swarm as a direction forms, finish in mesh to align on the output.

How long does convergence take? In a ring, one iteration carries a signal 2R positions, so full propagation takes ceil(N / 2R) iterations, and consensus roughly two to three times that, because agents observe, react, and confirm. The wall-clock column assumes an iteration interval of 30 seconds per agent loop, the default interval in the reference implementation. The interval is configurable per cluster.

Agents (N) Radius (R) Propagation ceil(N/2R) Consensus (2-3x) Wall clock to propagate
8 1 4 iterations 8-12 iterations about 2 minutes
100 2 25 iterations 50-75 iterations about 12 minutes
1,000 4 125 iterations 250-375 iterations about 62 minutes
1,000 20 25 iterations 50-75 iterations about 12 minutes

Radius trades per-agent context for convergence speed, as the last two rows show. For parallel map-style work, propagation barely matters. Agents only need to avoid duplicating each other. It costs you when the task needs consensus, so match radius and cluster size to the context you are in. The cost model follows the same logic: no always-on orchestrator and no broker. You pay for Kiro credits and the EC2 instances while they run, plus S3 storage and requests. You also pay for the AWS Lambda, Amazon API Gateway, and Amazon Bedrock usage the control plane and post-run analysis incur. See AWS Pricing.

None of this is new theory. Identical unreliable parts producing coherent global behavior through local reads is amorphous computing. Coordinating through traces left in a shared medium instead of messages is stigmergy, described by Grassé for termites in 1959 and formalized for artificial systems by Theraulaz and Bonabeau. And a set of append-only logs is a grow-only conflict-free replicated data type (CRDT) spreading gossip-style: replicas converge without locks, which is all the consistency this workload needs.

Where it breaks

Self-organizing clusters fail in ways orchestrated systems do not. With no supervisor to arbitrate, a bad signal can spread before anyone corrects it. Four failure modes recur, and each maps to a design choice rather than a safeguard bolted on afterward.

Failure mode Where it comes from Design choice that addresses it
Groupthink Mesh visibility collapses the cluster onto the first signal Open amorphous to build diversity, switch to mesh only to align
Drift Persistent session history builds behavioral momentum Fresh session per iteration. State lives only in shared logs
Hot spots Swarm with K too small for N starves subtasks Raise K, or switch to amorphous
Carry-over Stale files from a previous run read as current context Archive environment/ and store/ to history/ on every start

Drift deserves one more sentence, because it is the least obvious. An agent that keeps its session history carries a narrow reading of the direction forward even after its neighbors move on. Starting every iteration with no conversational memory sounds wasteful. It is actually the control that keeps a thousand independent loops steerable. The only state an agent carries is what it reads back from the shared logs.

Composing clusters

The same decision works one level up: clusters coordinate by reading each other’s shared environment, the way agents read each other’s logs. We run a structure we call WeltenBuilder: a feature cluster implements against an agreed interface, a shared-infrastructure cluster owns common services, a QA cluster reads across the others and reports inconsistencies as artifacts. A coordinator cluster writes conflict-resolution notes the others pick up on their next iteration. A resolution note is a trace, not a command. Remove the coordinator and you remove a signal, not a dependency.

Because the shared environment is the coordination plane, all clusters launch at the same time with no dependency graph to sequence. Contract bottlenecks dissolve the same way: a small mesh cluster converges on interface definitions in a few iterations while other clusters build against its latest stable output. This is where the pattern points: standing clusters, each producing one class of artifact, composed into a factory whose unit of work is a direction file and a topology.

kiro-flock WeltenBuilder dashboard showing several specialized clusters running at once, each with its own algorithm and agent count, beside the shared environment tree on the right.

Figure 3. Multiple specialized clusters in the WeltenBuilder dashboard, each with its own algorithm and agent count, coordinating only through the shared S3 environment on the right.

Try it

The kiro-flock reference implementation is open source under Apache 2.0. It is a sample to study and adapt, not a production system.

One setup script provisions the stack with the AWS Cloud Development Kit (AWS CDK): Amazon S3 for the shared environment, Amazon EC2 for the agents, and AWS Lambda with Amazon API Gateway as a control plane behind a dashboard. The dashboard starts and stops clusters, changes the algorithm, and updates the direction mid-run. Amazon Cognito handles access, and Amazon Bedrock backs a post-run analysis that summarizes how the cluster converged.

You need an AWS account with the AWS CDK bootstrapped. Install kiro-cli and create a Kiro API key for headless mode (requires a Kiro subscription). Then:

cp install.config.template install.config   # set REGION and PROFILE
./setup.sh

Direct a cluster in plain language: “Start a flock of 8 agents to review the files in my project and suggest improvements.” The default runs 8 agents at radius 1 and converged in 5 to 7 iterations in our runs. Before wider use, scope each agent’s EC2 AWS Identity and Access Management (IAM) role, restrict security-group egress to the endpoints agents should call, and add AWS Budgets alerts.

Conclusion

The supervisor pattern remains the right default for bounded task trees, whether you build it with Strands, Kiro CLI subagents, or any of the coding agents that delegate this way. When the work decomposes into many independent contributions and diversity matters more than a central gate, moving coordination into shared state helps remove the throughput ceiling and the single point of failure in one move. The convergence math and the failure modes both follow from that decision, and the distributed-systems results they rest on have been known for decades. Deploy the sample, read the logs as a cluster converges, and decide where your own multi-agent workloads belong.


About the authors

How GPU acceleration builds billion-scale vector indexes on Amazon OpenSearch Service

Post Syndicated from Navneet Verma original https://aws.amazon.com/blogs/big-data/how-gpu-acceleration-builds-billion-scale-vector-indexes-on-amazon-opensearch-service/

Modern search demands high-performance vector indexing and scalability to keep pace with the rapid growth of generative AI applications. As datasets grow into the billions, traditional CPU-based indexing often becomes a bottleneck, stalling productivity and innovation velocity.

With GPU-accelerated vector (k-NN) indexing now available on Amazon OpenSearch Service and Amazon OpenSearch Serverless, you can scale to billions of vectors efficiently. Powered by NVIDIA cuVS, an open-source library for GPU-accelerated vector search, this capability offloads compute-intensive vector index building to specialized GPU workers while your existing CPU infrastructure continues serving search. The result is faster, more cost-efficient construction of large-scale vector indexes without sacrificing query performance.

Our earlier post went into those performance and cost benefits in detail. This post goes a level deeper into how the capability works. We walk through the decoupled architecture that makes this possible. We explain how a GPU-built index is converted into one that your CPU data nodes can search with no quality tradeoff. We also show how the approach holds up at scale, with a benchmark of one billion 1024-dimensional vectors. Finally, we share the operational best practices we recommend for running GPU-accelerated index builds in production.

Use cases and benefits

As companies across industries build AI-powered and agentic applications to deliver richer customer experiences, GPU acceleration for vector indexing helps across a range of use cases. A few examples:

  • Adopt new embedding models faster: When an organization upgrades to a newer embedding model, every vector has to be regenerated and reindexed. At hundreds of millions to billions of vectors, a CPU rebuild can take days or weeks. GPU acceleration shortens that rebuild to hours, so you can move to a higher-quality model while significantly reducing the reindexing window and availability risk.
  • Accelerate large-scale reindexing: A global ecommerce application managing billions of product listings, customer reviews, and behavioral signals must rebuild its vector index rapidly as new products and embeddings are added. GPU acceleration completes this within a tight operational window, keeping search relevance current.
  • Absorb bursty or high-sustained writes: A media company covering a major sporting event, such as the World Cup or Olympics, needs to index millions of real-time embeddings simultaneously. These embeddings span match highlights, commentary clips, athlete profiles, and fan-generated content, and millions of viewers search for related content at the same time. GPU workers absorb the indexing burst without competing with CPU nodes serving live search traffic, avoiding the latency spikes that usually accompany heavy writes.
  • Right-size clusters for mixed read/write workloads: A retail system traditionally over-provisions its CPU cluster to handle both peak indexing loads during catalog refreshes and concurrent search traffic, paying for peak capacity around the clock. By offloading indexing to GPUs, the CPU cluster can be right sized for search alone, reducing infrastructure costs without sacrificing performance.
  • Speed up migrations to semantic search or to OpenSearch: Whether you’re converting a text-based corpus to vector embeddings for the first time or migrating an existing vector workload from another database to Amazon OpenSearch Service, GPU-accelerated indexing compresses what would be days of index building into hours, keeping pace with upstream GPU-powered embedding generation and minimizing cutover risk.

When does GPU acceleration activate?

GPU acceleration activates automatically once you opt in. On OpenSearch Service domains, you enable it by turning on the Vector Acceleration option, and from that point on, no changes to code or API flags are needed. On OpenSearch Serverless, GPU index-build acceleration is on by default for NextGen vector search collections. Figure 1 illustrates the index build workflow. OpenSearch automatically routes vector indexing operations to GPU or CPU based on segment size, optimizing performance and falling back to CPU if issues arise.

When OpenSearch flushes or merges a segment, it compares the segment’s vector data size against a configurable window bounded by index.knn.remote_index_build.size.min and index.knn.remote_index_build.size.max. The lower bound defaults to 50 MB. Segments above the lower bound are offloaded to a remote GPU worker, and smaller segments build locally on CPU. The segment vector size is calculated as:

segment_vector_size = num_vectors × dimensions × bytes_per_element

This means two workloads with identical document counts can produce different segment sizes:

Vectors Dimensions Encoding Segment Vector Size
100,000 1536 Float32 ~586 MB
100,000 768 Byte ~74 MB

Both examples exceed the default 50 MB lower bound, so with default settings both segments would be offloaded to a GPU worker.

Index build workflow showing OpenSearch routing each segment to a GPU worker or CPU based on its vector data size

Figure 1: Simplified flow for index builds

Decoupled indexing architecture

An OpenSearch index is internally divided into segments, each containing its own vector graph. This segment-level structure is what makes GPU offload practical. Each segment’s graph can be built independently on a GPU worker without coordinating across the full index. Building on this, the key architectural insight is separating where vectors are indexed from where they are searched. Existing CPU data nodes continue handling ingestion, search, and non-vector workloads. When a segment is ready for vector index construction, the heavy graph-building work is offloaded to dedicated GPU workers, and the finished index is returned to the data node for serving.

The index build workflow

  1. Ingest – Documents with vector fields are ingested into your OpenSearch Service domain or OpenSearch Serverless collection as usual. Vectors accumulate in segments on CPU data nodes.
  2. Offload – When a segment flushes or merges and its vector data falls within the GPU activation window, the data node uploads the raw vectors to Amazon Simple Storage Service (Amazon S3) and submits a build request.
  3. Build – A GPU worker from a managed warm pool picks up the job, loads the vectors, and builds the index using CAGRA (CUDA ANN Graph), the GPU-native graph algorithm in NVIDIA cuVS. The resulting CAGRA graph is then converted to a Hierarchical Navigable Small World (HNSW) graph compatible with CPU-based search.
  4. Return – The completed HNSW index is written back to Amazon S3 and downloaded by the data node, which then uses it to serve search queries.

Fully managed GPU index builds

Enable Vector Acceleration, and Amazon OpenSearch Service handles the rest:

Automatic scaling – GPU workers scale up and down automatically based on the number of pending build jobs. During a bulk ingest or reindex, more GPU workers spin up to handle the load. When the queue drains, they scale back to zero.

Automatic instance selection – The service selects the right GPU instance type for each build job based on segment size. No capacity planning or instance selection is required on your part.

Pay only for active builds – You’re charged only when GPUs are actively building indexes, not while they are idle. Even if Vector Acceleration is enabled on your domain or collection, GPU charges, measured in OpenSearch Compute Units (OCUs), apply only when segments reach the activation threshold and trigger an index build. There is no standing GPU infrastructure cost.

Your cost therefore scales directly with indexing activity. Bursty reindexing workloads consume GPU capacity for the duration of the build, and GPU cost returns to zero until the next build.

Figure 2 illustrates the decoupled GPU workflow. Amazon S3 acts as the intermediary between data nodes and GPU workers, allowing them to operate independently. Data nodes upload raw vectors to Amazon S3, GPU workers build the CAGRA graph and convert it to HNSW, and the completed index is returned to the data nodes for serving, with search running uninterrupted throughout.

Decoupled GPU workflow with Amazon S3 as the intermediary between CPU data nodes and GPU workers that build and convert the index

Figure 2: GPU index flow architecture

Inside the CAGRA-to-HNSW conversion

In the previous section, we described how GPU workers build the vector index and return it to data nodes. But how does a GPU-built graph become searchable on CPU, and does this conversion sacrifice quality? The short answer: it doesn’t.

The CAGRA algorithm

The GPU workers use the CAGRA algorithm integrated through the cuVS GPU backend of the Facebook AI Similarity Search (Faiss) library. CAGRA is a graph-based indexing approach built from the ground up for GPU acceleration. It first builds a k-NN graph using another approximate nearest neighbors method like Inverted File with Product Quantization (IVF-PQ) or Nearest Neighbor Descent (NN-Descent). It then removes redundant paths between neighbors to form a navigable search graph.

Construction flow of the CAGRA graph, from an initial k-NN graph to a pruned, navigable search graph

Figure 3: Construction flow of the CAGRA graph

Source: CAGRA: Highly Parallel Graph Construction and Approximate Nearest Neighbor Search for GPUs

How the GPU worker builds the index

When the GPU workers receive a vector index build request, it carries the necessary parameters for constructing the segment-specific vector index. The vector index build component initiates the process by retrieving the vector file from Amazon S3 and loading it into CPU memory. These vectors are then used to construct a CAGRA index using Faiss. After constructing the CAGRA index on GPU, the system converts it into an HNSW graph format for compatibility with CPU-based search operations. The resulting index is uploaded to Amazon S3, completing the build request.

Converting the CAGRA graph to HNSW

A typical HNSW index is a multilayered hierarchical graph. The bottom layer (layer 0) of the graph contains the vectors, and the upper layers are sparse subsets used solely for navigation. They help the search algorithm find a good entry point into the bottom layer. However, our HNSW implementation uses the CAGRA graph as the bottom layer and, similar to the CAGRA search method, starts with random entry points into the graph, avoiding the need for the upper layers altogether.

This means the GPU handles the heavy lifting of building the base-layer graph. Reusing that graph as the HNSW base layer avoids rebuilding it on the CPU, which keeps conversion overhead low. As Figure 4 shows, the CAGRA graph becomes the base layer. At query time, the search selects a random set of nodes in the graph and traverses it by following the nearest neighbor links. This is known as greedy search.

Searching an HNSW-converted CAGRA graph by starting at random entry nodes and following nearest neighbor links

Figure 4: Searching an HNSW-converted CAGRA graph

Same recall, faster build

Previous benchmarks have confirmed that GPU-built indexes achieve the same recall as CPU-built HNSW with no quality tradeoff. This is because the bottom-layer graph structure produced by CAGRA is equivalent in connectivity and search quality to what HNSW constructs on CPU. Only the build method differs.

Scaling beyond GPU memory

Out-of-core construction

Traditional GPU indexing requires the entire dataset to reside in GPU memory, creating a hard ceiling on index size based on available hardware. CAGRA removes this limitation through out-of-core k-NN graph construction. When IVF-PQ is used to build the initial k-NN graph for CAGRA, data is streamed from system memory to the GPU in batches, so the full dataset never needs to fit in GPU memory at once. Meanwhile, the GPU still handles the computationally intensive distance calculations and graph optimization.

Quantization

GPU-accelerated indexing supports the quantization levels available in OpenSearch, including 2×, 8×, 16×, and 32× compression. Quantization is applied before vectors are sent to the GPU. This reduces both the data transfer size to GPU workers and the memory footprint during graph construction. This means that you can build indexes over larger segments, improving cost efficiency.

Indexing one billion 1024-dimensional vectors on the GPU

Dataset setup

To evaluate a realistic large-scale workload, we used a dataset containing one billion vectors in 1024 dimensions. Because uniformly random vectors yield misleading results for both index construction and recall, we required data that maintained the structure of real-world embeddings. We created this dataset using the cuVS synthetic dataset generator in cuvs-bench, which outputs synthetic data whose distribution mimics an actual embedding dataset derived from Common Crawl. You can use this approach to build a realistic dataset without exposing or distributing sensitive original data. The generator can produce the complete one-billion-vector dataset, 10,000 query vectors, and the associated ground-truth labels in roughly two hours on a single Amazon Elastic Compute Cloud (Amazon EC2) g6e.16xlarge instance.

Cluster configuration

We designed the benchmark cluster on OpenSearch Service following OpenSearch vector search performance tuning best practices and conducted the benchmark using the OpenSearch Benchmark framework.

Setting Value Rationale
Data Nodes 24 × r8g.4xlarge Memory-optimized instances for large vector indexes
Primary shards 48 Keeps shard size manageable and maximizes parallelism
Replicas 0 Maximizes indexing throughput. Replicas added after build
GPU workers 10 (pre-scaled) Avoids cold-start effects during measurement
Bulk clients 160 Saturates ingestion pipeline across 24 nodes
Bulk size 500 docs/request Balances per-request overhead vs. memory pressure
Refresh interval -1 (during ingest) Prevents small segment creation. Force merge after ingesting
Merge autothrottle Disabled Avoids artificial bottleneck during benchmark

Key best practices applied

  1. Memory-optimized instances – r8g.4xlarge provides sufficient heap and native memory for loading HNSW graphs post-build.
  2. Disabled refresh during bulk ingest – Prevents creation of many small segments that would each trigger individual GPU builds.
  3. High number of bulk clients – Saturates ingestion across nodes and makes sure that GPUs are busy building the indexes.

We used the default HNSW build and search settings in OpenSearch (such as m and ef_construction) since the defaults are what most users start with, and they keep the benchmark representative.

Benchmark results

Dataset Index (min) Recall @k=100 Recall @1 P50 (search) P90 (search) P99 (search) Vector Acceleration OCU Used
1024D 1B 274 0.93 0.93 26.47ms 32.5ms 66.6ms 44

Build time scales linearly with data volume

Our earlier benchmark on OpenSearch Service indexed one billion 128-dimensional vectors (BigANN SIFT dataset) in approximately 35.5 minutes. In our latest benchmark, we scaled dimensionality 8x to 1024 dimensions and completed the index build in 274 minutes, roughly proportional to the increase in data volume. This demonstrates that GPU acceleration maintains consistent throughput efficiency as dimensionality grows: build time scales with data volume rather than fixed startup costs, so you can predictably estimate index build time from your dataset size. Search latency also stayed low at this scale, so the resulting index supported responsive queries without trading away build speed.

Optimizing bulk ingestion for GPU-accelerated indexing

When loading large volumes of vector data, temporarily adjusting index behavior can significantly reduce GPU processing overhead. This approach works if your use case can tolerate a brief period of data staleness. During full index builds, this is generally acceptable, because newly ingested vectors are not searchable until you re-enable refresh. By disabling refresh during bulk ingestion ("index.refresh_interval": "-1"), you prevent the continuous creation of small segments. Each of these would otherwise trigger an individual GPU build job. After ingestion is complete, we enable the refresh interval and complete the refresh to make the segment searchable. This means the GPU builds the vector index once across large, well-packed segments rather than repeatedly across many small ones, resulting in faster overall indexing throughput.

After enabling GPU acceleration, you can monitor builds through Amazon CloudWatch metrics (cluster-level) and the OpenSearch k-NN Stats API (per-node). If a GPU build fails, the system automatically falls back to CPU-based index building, so your data remains indexed.

Future optimization

Today, the completed HNSW index (graph structure and vectors) is transferred back from GPU workers to data nodes through Amazon S3. Because data nodes already hold the raw vectors locally, a future optimization will transfer only the graph structure (neighbor lists). This significantly reduces the data written back to Amazon S3 and the download time to data nodes.

Conclusion

GPU-accelerated indexing lets you build billion-scale vector indexes on Amazon OpenSearch Service in hours instead of days, without changing how queries are served on both OpenSearch Service domains and OpenSearch Serverless collections. In this post, we showed how OpenSearch Service offloads eligible index builds to GPU workers, builds a CAGRA graph through the NVIDIA cuVS backend in Faiss, and converts it into a CPU-searchable HNSW index. We then demonstrated the approach at scale on one billion 1024-dimensional vectors, and shared best practices for optimizing bulk ingestion and monitoring build activity and OCU usage.

Get started

Ready to try GPU-accelerated vector indexing? In a supported AWS Region, you can enable GPU acceleration when you create or update an OpenSearch Service domain running OpenSearch 3.1 or later. Use the AWS Management Console, AWS Command Line Interface (AWS CLI), or AWS SDK. For a new OpenSearch Serverless deployment, create a NextGen vector search collection, where GPU index-build acceleration is enabled by default and can be controlled for individual indexes. For a Classic vector collection, enable GPU acceleration at the collection level.

Acknowledgments

The authors would like to thank Ben Gardner, Manas Singh, Zack Meeks, Jiahong Liu, James Yi, Jinsol Park from NVIDIA for their contributions to this post.


About the authors

Navneet Verma

Navneet is a Principal Software Engineer at AWS working on core Vector Search in OpenSearch. He is passionate about scale, performance, and advancing the state of vector search for large-scale AI workloads.

Vamshi Vijay Nakkirtha

Vamshi Vijay Nakkirtha

Vamshi is a software engineering manager working on the OpenSearch Project and Amazon OpenSearch Service. His interests center on distributed systems.

Gowri Balasubramanian

Gowri Balasubramanian

Gowri is a Senior Manager leading the Data Specialist Solutions Architect team at Amazon Web Services. He drives customer adoption of AWS database and analytics services and develops prescriptive guidance, from reference architectures to best practices, to help enterprises accelerate their data and AI transformation journeys. He is passionate about scalable and distributed data systems.

Kshitiz Gupta

Kshitiz Gupta

Kshitiz is a Senior Solutions Architect at NVIDIA, where he helps cloud customers optimize large-scale AI workloads on GPUs. His work spans GPU-accelerated data processing, vector search, and LLM inference partnering closely with AWS and Amazon teams to bring these capabilities into production. Outside of work, he enjoys music, yoga, and hiking.

Corey Nolet

Corey Nolet

Corey is a distinguished engineer for vector search, data mining, and classical ML libraries at NVIDIA, where he focuses on building and scaling algorithms to support extreme data loads at light speed. Prior to joining NVIDIA in 2018, Corey spent many years building massive-scale exploratory data science & real-time analytics platforms for big data and HPC environments in the defense industry. Corey holds a PhD in Computer Science and has a passion for using data to make better sense of the world.

Rajeshwari Devaramani

Rajeshwari is a solutions architect at NVIDIA. Rajeshwari holds a master’s degree in computational science and engineering from the Georgia Institute of Technology. Her background includes GPU programming, high-performance computing, and deep learning.

Automate SageMaker HyperPod incident triage and root-cause-analysis with AWS DevOps Agent

Post Syndicated from Tomonori Shimomura original https://aws.amazon.com/blogs/devops/automate-sagemaker-hyperpod-incident-triage-and-root-cause-analysis-with-aws-devops-agent/

Introduction

Large-scale machine learning workloads: training, fine-tuning, and inference run on clusters of hundreds to thousands of GPU instances for days or weeks at a stretch. Keeping operational visibility across a fleet of this size is a constant challenge: hardware health events, node lifecycle transitions, capacity fluctuations, and workload-level issues appear in the event stream around the clock, including nights and weekends.

Amazon SageMaker HyperPod is a purpose-built managed cluster service that lets you run distributed model training, fine-tuning, and inference across hundreds of accelerated instances. It provides built-in resiliency that automatically detects and replaces faulty hardware, so long-running jobs can continue with minimal interruption.

For teams operating these clusters, the scale still creates a fundamental tension: you need continuous visibility into your fleet, but you can’t afford to keep engineers watching the event stream 24/7. 

What HyperPod resiliency already handles

SageMaker HyperPod’s built-in resiliency layer automatically detects and self-heals instance-level GPU failures. When the Health Monitoring Agent (HMA) identifies a bad GPU, the HyperPod resiliency layer drains, reboots, or replaces the node depending on the error type, and the job resumes without human intervention. This is exactly what you want: routine hardware failures are handled automatically so your training runs keep going. 

This solution does not replace HMA or any part of HyperPod’s resiliency. It adds an autonomous investigation layer on top, using the cluster events and health signals that HMA and HyperPod already produce as its input. 

Operational conditions where a human still wants to be in the loop 

With that self-healing in place, there are operational conditions where a human still wants to be in the loop or decide: 

  • Configuration issues: a lifecycle-script change you made, a misconfigured mount, or a networking/security change that causes provisioning failures on every new node. 
  • Capacity conditions: a replacement waiting on capacity in the pool, where the operator needs to know recovery is in flight and can decide whether to intervene. 
  • Recurring hardware faults: each fault self-heals correctly, but the same GPU error signature recurring across three or more replacements on one instance group in a week is a pattern worth surfacing to an operator as a single signal. 
  • Workload-level conditions: Pods stuck in CrashLoopBackOff for hours, nodes sitting NotReady, or GPU allocation chronically low. 

Without automation, these conditions push operators into round-the-clock manual triage: correlating events across the SageMaker control plane, Amazon EKS, and Amazon CloudWatch, and deciding whether HyperPod is still recovering or needs a hand. 

Opportunity: AWS DevOps Agent as a 24/7 companion 

AWS DevOps Agent provides an autonomous incident-response platform that can be taught a domain’s operational model through custom skills. By wiring your HyperPod cluster into DevOps Agent, you get a 24/7 companion that complements HyperPod’s self-healing. It watches for the operational conditions that still need a human decision, triaging them, root-causing them, and delivering a clear verdict with recommended actions. 

By design, DevOps Agent is configured to run in observe-and-report mode for this integration – it is not granted SSM, SSH, or action-taking permissions against your cluster or its nodes. The agent reads cluster events, control-plane state, Kubernetes objects, and CloudWatch logs to reconstruct what happened; every corrective action (node reboots, replacements, drains) continues to be performed by HyperPod’s own resiliency layer or by an operator responding to the emailed verdict. This read-only boundary is deliberate: it keeps the agent’s blast radius zero while still delivering the correlation and triage value. 

​​In this post, you will learn how to connect any SageMaker HyperPod cluster (either the EKS or Slurm Orchestrator option) to AWS DevOps Agent. Conditions are auto-detected, triaged, root-caused from cluster state and CloudWatch logs, and emailed as a clear verdict. You will also see how the solution can be extended to detect additional conditions specific to your workloads.​ 

Solution Overview 

What this solution delivers 

This solution wires any SageMaker HyperPod cluster into AWS DevOps Agent so that operational conditions calling for a human decision are auto-detected, triaged, root-caused, and delivered as a human-readable verdict email. Specifically, you get: 

  • Autodetection of HyperPod conditions that complement resiliency self-healing, from the live SageMaker event stream and a periodic Kubernetes-state audit. 
  • Triage + root-cause analysis by the DevOps Agent, taught HyperPod’s operational model via two custom skills. It reconstructs the incident timeline and decides whether HyperPod is still recovering or needs an operator. 
  • Human-readable verdict emails: Monitor (recovery in flight, here’s the ETA), Escalate (you need to act, here’s why and what to do), or Resolved (auto-recovery closed the loop). Noise is filtered out. 
  • Extensibility: customize what conditions are detected (by modifying the periodic-audit Lambda) and how the agent reasons about them (by editing the plain-English skills). 

The following screenshot shows the DevOps Agent incident response dashboard with example verdict emails for three common fault types: 

DevOps Agent incident response dashboard showing investigation list and timeline, with three email verdict examples for GPU NVLink fault, lifecycle-script bootstrap failure, and insufficient-capacity errors

DevOps Agent incident response dashboard showing investigation list and timeline, with three email verdict examples for GPU NVLink fault, lifecycle-script bootstrap failure, and insufficient-capacity errors

Architecture 

The whole solution deploys one AWS CloudFormation stack per cluster. Two event paths feed the DevOps Agent, and one path carries its verdicts back out to you. 

Architecture diagram showing the event flow from HyperPod Health Monitoring Agent through EventBridge to DevOps Agent and email notification

Architecture diagram showing the event flow from HyperPod Health Monitoring Agent through EventBridge to DevOps Agent and email notification

This architecture shows a 1:1 relationship between a HyperPod cluster and a DevOps Agent space, and the deployment instructions in this post follow that model. If you need to associate multiple clusters with a single Agent Space, you can customize the CloudFormation template and the ClusterFilter parameter to widen the allowlist of cluster names forwarded by the webhook bridge.

Event flow 

  1. Event-driven issue detection: HyperPod emits cluster-state, node-health, and capacity events to Amazon EventBridge. The webhook bridge Lambda drops routine Info-level noise, maps the rest into a DevOps Agent investigation payload, signs it with HMAC-SHA256 using a shared secret stored in AWS Secrets Manager, and POSTs it to the agent’s generic webhook. 
  1. Polling-based issue detection: A periodic-audit Lambda checks Kubernetes state (CrashLoopBackOff pods, NotReady nodes) every 15 minutes and fires only when it finds a real issue, plus a daily heartbeat confirming the pipeline is alive. On a healthy cluster, nothing is POSTed, so no investigation runs and no cost is incurred. 
  1. Investigation: DevOps Agent receives the payload and runs two custom skills: the triage skill decides whether to link (duplicate), skip (noise), or proceed (investigate). The RCA skill reconstructs the timeline using describe-cluster, list-cluster-nodes, list-cluster-events, kubectl, and CloudWatch logs (HMA health monitoring, lifecycle scripts), then classifies the incident as Suppress, Monitor, Escalate, or Resolved. 
  1. Notification: An Amazon Lambda function sends notification emails via Amazon SES. It listens on the aws.aidevops event stream for investigation completions, reads the verdict from the agent’s journal, and sends an email with the headline, what happened, likely cause, and recommended action. Suppress verdicts are filtered to avoid noise on healthy clusters. 

​​Getting started​ 

For a step-by-step walkthrough to deploy this solution, visit the DevOps Agent Integration guide. Once you have the solution running, the following sections explain how to customize detection, reasoning, and notifications for your environment. 

Prerequisites 

  • An AWS account with AWS CLI v2 configured for the target region. 
  • An existing SageMaker HyperPod cluster (EKS or Slurm orchestrator). 
  • IAM permissions to create roles, deploy CloudFormation, manage Secrets Manager, and call devops-agent:* and eks:CreateAccessEntry. 
  • For email notifications: a verified Amazon SES sender identity. You can verify an email address in the Amazon SES console or with the AWS CLI. After running the command below, the address owner will receive a verification email and must click the confirmation link:

    aws ses verify-email-identity --email-address [email protected]

    Recipients must also be verified if your SES account is still in sandbox mode. 

Deploying with CloudFormation

The solution deploys as a single CloudFormation stack. Clone the awsome-distributed-ai repository, create a params.json with your cluster name and email settings, and run: 

cd 1.architectures/5.sagemaker-hyperpod/tools/devops-agent

# 1. Set up a Python env with boto3 >= 1.43.25
python3 -m venv .venv && source .venv/bin/activate && pip install 'boto3>=1.43.25'

# 2. Fill in your cluster name and email addresses
cp deploy/params.example.json deploy/params.json
# edit: HyperPodClusterName, EmailSender, EmailRecipients 

# 3. Deploy
make deploy

This provisions the Agent Space with read-only EKS access (auto-discovered from the cluster’s orchestrator ARN), the EventBridge rule and webhook bridge Lambda, the periodic-audit scheduler, and the email notifier. For Slurm-orchestrated clusters, the EKS access step is skipped automatically. 

The webhook bridge — mapping HyperPod events to DevOps Agent 

An EventBridge rule captures HyperPod events and invokes a Lambda function. The Lambda forwards all Warn and Error level events, normalizing each into a DevOps Agent investigation payload. It extracts the failure message, instance group, and event metadata, then signs it with HMAC using a shared secret stored in AWS Secrets Manager, and POSTs it to the agent’s generic webhook endpoint. Info-level events are dropped at the bridge to avoid creating investigations for routine status updates. 

A cluster allowlist parameter lets you scope which HyperPod clusters trigger investigations, useful when multiple clusters share the same account and region. 

How the skills are defined — teaching the agent HyperPod’s operational model 

AWS DevOps Agent skills are plain-English instructions that teach the agent how to reason about a domain. This solution includes two complementary skills: 

Triage skill — LINKED / SKIPPED / PROCEED (view the skill document) 

The triage skill runs first on every incoming task. It decides whether to link the event to an existing investigation, skip it, or proceed to a full investigation. 

  • Why triage matters — a concrete example: When a single node fails, HyperPod’s replacement process emits multiple events in quick succession: “lost orchestration-ready status,” “provisioning started,” “capacity request initiated.” Without triage, each event would spawn a separate investigation. The triage skill recognizes these events belong to the same incident (same instance group + overlapping time window) and links them, so only one investigation runs. This saves investigation compute and avoids duplicate emails. 
  • When to SKIP: When a node is already being replaced and a follow-up “lost orchestration-ready status” event arrives with a generic “Request to service failed” message, the triage skill recognizes that a replacement is already in progress for that instance group and skips the event. No new investigation is created for what is simply a progress update of an existing recovery. 

RCA skill — timeline reconstruction and verdict (view the skill document) 

When triage produces PROCEED, the RCA skill takes over. It reads cluster state, events, and logs, reconstructs an incident timeline, and classifies the situation into one of four verdicts:

 RCA Flowchart showing the four phases of root-cause analysis: data gathering, timeline reconstruction, classification, and recurrence check

RCA Flowchart showing the four phases of root-cause analysis: data gathering, timeline reconstruction, classification, and recurrence check

  • Phase 1 — Data gathering: The skill reads describe-cluster, list-cluster-nodes, list-cluster-events, and CloudWatch log streams (HMA health monitoring, lifecycle scripts) to collect the raw facts. 
  • Phase 2 — Timeline reconstruction: It orders events chronologically and identifies the fault chain: what triggered what, which nodes were affected, and what recovery actions HyperPod took. 
  • Phase 3 — Classification: Based on the timeline, recurrence statistics, and HyperPod’s resiliency behavior, it assigns a verdict: 
    • Suppress — a non-issue (for example, a transient event that has already resolved). 
    • Monitor — recovery is in flight; here’s the expected resolution window. 
    • Escalate — you need to act; here’s the root cause and recommended action. 
  • Resolved — auto-recovery closed the loop; no action needed. 
  • Phase 4 — Recurrence check: The skill computes sliding-window statistics over the one week cluster event history. When thresholds are crossed, the verdict escalates to alert the operator of a systemic pattern. For example, the same GPU error signature on the same instance group three or more times in a week, or five or more replacements fleet-wide in 24 hours. 

The verdict is written to the agent’s investigation journal along with a human-readable report containing what happened, the likely cause, and recommended operator actions. 

The periodic-audit Lambda — Kubernetes state monitoring 

The periodic-audit Lambda fires every 15 minutes and inspects Kubernetes Pod/Node state directly (via the EKS API server). It checks for: 

  • Pods in CrashLoopBackOff (default: flagged when restart count reaches five and the last crash is within 15 minutes) 
  • NotReady nodes (default: flagged when a node has been NotReady for at least 15 minutes and at least 10% of nodes are affected) 

Namespace-aware filtering controls which pods are checked: 

  • Pods in kube-public and kube-node-lease are ignored entirely by default. 
  • Pods in kube-system, aws-hyperpod, and amazon-cloudwatch are tagged as system-workload issues (distinct from user-workload issues in the verdict). 

All thresholds and namespace lists are configurable via the CloudFormation stack parameters. 

The Lambda POSTs a webhook event to DevOps Agent only when a real issue is found. On a healthy cluster, nothing is POSTed, so no investigation runs and no cost is incurred. A separate daily heartbeat schedule confirms the monitoring pipeline itself is alive. The heartbeat is visible in the DevOps Agent console but deliberately not emailed on healthy runs — so silence in your inbox means the cluster is healthy, not that the pipeline is broken. 

Note: HyperPod infrastructure faults (node health, capacity errors, lifecycle-script failures) are handled event-driven by the webhook bridge. They come from the native HyperPod event stream in EventBridge. The periodic audit deliberately does not duplicate that path; it only covers Kubernetes workload state, which is not in the HyperPod event stream. 

Closing the loop — the email notifier

An EventBridge rule on the aws.aidevops event stream captures investigation lifecycle events. The email-notifier Lambda processes these events through the following steps: 

  1. Event filtering: Only “Investigation Completed” events are processed (one email per investigation lifecycle). The event payload contains the agent_space_id, task_id, and execution_id. 
  2. Dedup: The Lambda checks an S3 marker at s3://<bucket>/emailed/<execution_id>. If present, this investigation has already been emailed and the event is dropped. This prevents duplicate emails when the same completion event is re-emitted. 
  3. Fetching the investigation context: The Lambda calls two DevOps Agent APIs: 
    • get_backlog_task(agentSpaceId, taskId) — retrieves the task metadata (title, priority, timestamps). 
    • list_journal_records(agentSpaceId, executionId) — retrieves the investigation’s findings, symptoms, and investigation gaps from the agent’s journal. 
  4. Suppress-verdict filtering: If the investigation produced a Suppress verdict or no findings at all, no email is sent. 
  5. Email composition: The Lambda composes a single HTML email from the journal records: a short headline followed by a one-paragraph summary covering what happened, the likely cause, and the recommended action. 
  6. Send via SES: The formatted email is sent to the configured recipients. After successful delivery, the S3 dedup marker is written. 

The operator also has access to the full investigation in the DevOps Agent web console (see following “Viewing investigations” section). 

Viewing investigations in the DevOps Agent console 

For readers new to AWS DevOps Agent, here’s how to navigate to your investigations: 

  1. Open the AWS DevOps Agent console. 
  2. Select your Agent Space (named hyperpod-<cluster-name>-devops-agent by default). 
  3. From the Launch web app drop-down, choose an option to open the DevOps Agent web app. 
  4. Select Incidents from the left navigation pane to open the Incident Response Dashboard. It lists all investigations with their subject, status, and timestamp. 
  5. Select any investigation to see its full timeline, journal records, and the verdict report. 

Asking the agent directly — the DevOps Agent Chat UI 

Beyond the automated emails, you don’t have to wait for the next investigation to get answers about your cluster. You can open the DevOps Agent’s AI chat at any time and ask follow-up questions in plain English. The agent answers from the live cluster state, the investigation history, and the skills it has been taught. 

For example: 

  • “I got an email about a GPU failure in my cluster. Did it get resolved now with HyperPod’s resiliency?” — The agent checks the current cluster state, confirms whether the replacement succeeded, and provides a timeline of what happened (HMA detection → replacement initiated → node back in service), along with anything to watch for. 
  • “Are there unhealthy Pods on my cluster?” — The agent inspects the Kubernetes state and reports any CrashLoopBackOff pods or NotReady nodes. 
  • “I just triggered scaling up. Check if it is progressing well.” — The agent looks at the cluster’s current node counts vs. target counts and reports whether provisioning is on track. 
AWS DevOps Agent chat interface showing a natural language query about cluster health

AWS DevOps Agent chat interface showing a natural language query about cluster health

The chat conversations are stored per Agent Space, so you can revisit past interactions alongside the automated investigations. This makes the Agent Space a single pane of glass for both automated incident response and ad-hoc troubleshooting of your HyperPod cluster. 

Extending the solution — detection vs. reasoning 

The solution has two extension points, which serve different purposes: 

  1. Extending detection (what conditions are caught): 
    • Event-driven path: The webhook bridge Lambda drops Info-level events and forwards all Warn and Error level HyperPod events to DevOps Agent. This typically does not need modification. It already catches all actionable events. 
    • Polling-based path: The periodic-audit Lambda checks Kubernetes state. To detect additional conditions (for example, GPU allocation below a threshold or specific Pod labels stuck in error states), add that logic to the Lambda code. 
  2. Extending reasoning (how the agent investigates and classifies): edit the plain-English skill definitions. For example, you can teach the RCA skill new classification rules, add domain-specific context about your workload’s expected behavior, or adjust the recurrence thresholds. 

Detection is code; reasoning is natural language. Both are in the repo and designed to be customized independently. 

Investigation feedback 

After each investigation completes, a Feedback button appears in the DevOps Agent console. Clicking it opens the Investigation feedback dialog, where you can: 

  • Rate whether the root cause was correct 
  • Indicate whether human steering was needed during the investigation 
  • Provide written feedback explaining what could be improved 

This structured feedback is stored per investigation. An auto-learning mechanism that uses this feedback to improve future investigations is actively being developed. 

DevOps Agent APIs used by this solution 

For readers interested in the programmatic integration, here are the key DevOps Agent APIs this solution calls:

Component API Purpose
Webhook provisioner (deployment) register_service Register the generic webhook service with DevOps Agent
Webhook provisioner (deployment) associate_service Associate the webhook with the Agent Space
Skill uploader (deployment) list_assets Check if a skill already exists
Skill uploader (deployment) create_asset / update_asset Upload or update the triage and RCA skill definitions
Email notifier (runtime) get_backlog_task Retrieve task metadata (title, priority, timestamps)
Email notifier (runtime) list_journal_records Retrieve findings, symptoms, and gaps from the investigation journal
Teardown disassociate_service / deregister_service / delete_asset Clean up on stack deletion

Cleaning up 

To remove all resources created by this solution, run: 

make teardown-stack

This deletes the CloudFormation stack, removes the Agent Space, EKS access entries, secrets, and email configuration.

Additionally, if you no longer need the prerequisite resources, you can revert their setup, for example, deleting the verified Amazon SES email address identities you created for notifications.

Cost considerations 

​​​This solution is designed to be near-zero cost on a healthy cluster and scales proportionally with fault volume. Cost scales with fault volume, not node count directly. At large scale (100+ nodes), the triage skill becomes critical. A single hardware fault can generate 5-10 correlated EventBridge events, most of which are filtered by the webhook bridge Lambda before reaching the agent. Where triage adds value is linking and deduplicating across similar faults that affect multiple instances, or repeated faults on the same instance over time, consolidating them into a single investigation instead of many. As an example, a 500-node training cluster might see 20-50 investigations per month after filtering and deduplication.​​ 

  1. ​​​Filtering and triage are your cost savers at scale. The webhook bridge filters correlated events from a single node failure (5-10 EventBridge events reduced to 1 forwarded event), eliminating redundant investigations at the source. Triage then links similar faults across multiple instances into a single investigation. For example, if 5 nodes hit the same GPU error in a window, triage consolidates them into 1 investigation instead of 5 (saving 4 × $4 = $16). The bigger the cluster, the more both layers save.​​ 
  2. Investigation duration grows sub-linearly. A 1000-node cluster investigation doesn’t take 100x longer than a 10-node one. The agent queries describe-cluster and list-cluster-events once regardless of size. The data returned is bigger, but the API call count is similar. 
  3. CloudWatch Logs queries are the variable. On large clusters, the agent may query more HMA log streams, which takes longer agent-seconds AND incurs CloudWatch Logs Insights charges on your account (not part of DevOps Agent pricing). 

DevOps Agent (the primary cost driver): Estimates based on 2 accelerator instances in a cluster 

Component Pricing Your cluster estimate
Investigations $0.0083/agent-second ~$4/investigation (at 8 min avg)
Chat (on-demand SRE tasks) $0.0083/agent-second ~$0.25/chat query (at 30 sec avg)
Daily heartbeat $0.0083/agent-second ~$1-2/day (short investigation confirming health)

On a healthy cluster with no faults, only the daily heartbeat fires, approximately $30-60/month in DevOps Agent time. On a cluster experiencing 5 real faults per week (typical for a large GPU fleet), expect ~20 investigations/month × $4 each = $80/month in investigation costs.

Free tier and credits:

New DevOps Agent customers receive a 2-month free trial (20 hours of investigations, 20 hours of chat per month). Enterprise Support customers receive monthly credits equal to 75% of their AWS Support charge toward DevOps Agent usage. 

Supporting infrastructure (secondary costs): 

Component Monthly Cost Estimates
Lambda invocations ~96/day (15-min audit) + event-driven = well within free tier
S3 (skills + dedup markers) < $0.01 (a few MB total)
Secrets Manager (1 secret) $0.40
EventBridge rules Negligible (per-event pricing)
SES emails $0.10/1000 emails — at most 1 per investigation
CloudWatch Logs (Lambda) < $1 (minimal log volume)

Total estimated monthly cost: 

Scenario DevOps Agent Infrastructure Total
Healthy cluster (no faults) ~$30-60 (heartbeat only) < $2 ~$32-62/month
Moderate faults (5/week) ~$80-120 < $2 ~$82-122/month
Heavy faults (20/week) ~$320-400 < $5 ~$325-405/month

How cluster size impacts cost 

Factor Small cluster (1-10 nodes) Large cluster (100-1000 nodes)
Fault frequency Rare (maybe 1-2/week) Constant (NVIDIA reports ~1 fault/2-3 hours at 10K GPU scale)
Events per fault Few (1 node replacement = 3-5 events) More (cascading replacements, capacity queuing)
Investigation duration Shorter (less state to read, fewer events in timeline) Longer (more nodes to describe, more events to correlate, larger CloudWatch log groups to query)
Triage value Low (few duplicates) High (one fault generates many correlated events — triage links them into 1 investigation)
Periodic audit Fast (few pods/nodes to check) Slower (more K8s state to inspect)
Cluster Size Faults/month Investigations Est. Agent Cost
1-10 nodes (your test) 2-5 2-5 + heartbeat $8-20/mo + ~$30 heartbeat
10-50 nodes (typical prod) 5-20 5-15 (triage dedup) $20-60/mo + ~$30 heartbeat
100-500 nodes (large training) 50-200 20-50 (heavy triage) $80-200/mo + ~$45 heartbeat
1000+ nodes (frontier) 200-700 50-100 (massive dedup) $200-500/mo + ~$60 heartbeat

Cost control levers: 

  1. Disable the periodic audit (EnablePeriodicAudit: false) to eliminate the heartbeat cost. Live event bridging still works. 
  2. Triage (LINK/SKIP decisions) runs at task creation time. No investigation cost is billed for deduplicated or skipped events. 
  3. Suppress verdicts filter email notifications but the investigation still runs. If you want to eliminate that cost, tune your EventBridge rule to drop more event types at the bridge level. 

Comparison to manual monitoring: 

Without automation, each fault requires an on-call engineer to manually correlate events across CloudWatch, EKS, and the SageMaker console, typically 30-45 minutes of triage before they even know whether HyperPod is self-healing or needs intervention. This solution delivers a root-caused verdict in minutes at ~$4 per investigation, while providing 24/7 coverage without human wake-ups. The cost savings compound with cluster scale: at 20 faults per month, that’s 10-15 hours of engineering triage replaced by automated verdicts. 

Conclusion 

In this post, we showed how to build an end-to-end agentic incident-response pipeline for SageMaker HyperPod using AWS DevOps Agent. The solution complements HyperPod’s built-in resiliency by watching for the operational conditions where a human still wants to be in the loop: configuration issues affecting provisioning, capacity-bound recoveries, recurring hardware fault patterns, and workload-level conditions. It delivers clear, root-caused verdicts to the operator’s inbox. 

The broader takeaway is a reusable pattern: teaching an AI agent a domain’s operational model through plain-English skills, so it can distinguish “the system is recovering on its own” from “this needs a human decision.” This pattern applies beyond HyperPod to any event-driven AWS service where operational conditions benefit from automated correlation and triage. 

What’s next 

​​​To deploy the solution, follow the step-by-step instructions in the DevOps Agent Integration guide on the AI on SageMaker HyperPod site. Once it’s running, you can customize it for your environment:​​ 

  • Adjust the CloudFormation parameters: tune the periodic-audit schedule, CrashLoopBackOff thresholds, NotReady node percentages, namespace filtering, and email recipients. No code changes required. 
  • Extend detection: modify the periodic-audit Lambda to check for additional Kubernetes conditions specific to your workloads (for example, GPU allocation below a threshold, specific Pod labels stuck in error states). 
  • Extend reasoning: edit the triage or RCA skill definitions to adjust classification rules, add domain context about your expected cluster behavior, or tune the recurrence thresholds. 
  • Add notification channels: connect Slack or PagerDuty via DevOps Agent’s built-in integrations or via a sibling EventBridge rule on the same aws.aidevops event stream. 

The skills are plain English. Iterate on them the same way you’d iterate on a runbook. 

About the authors

Tomonori Shimomura is a Principal Solutions Architect on the Amazon SageMaker AI team, where he provides in-depth technical consultation to SageMaker AI customers and suggests product improvements to the product team. Before joining Amazon, he worked on the design and development of embedded software for video game consoles, and now he leverages his in-depth skills in Cloud side technology. In his free time, he enjoys playing video games, reading books, and writing software.

Mayank Gupta is a Senior AI/ML Specialist with deep expertise in machine learning frameworks and enterprise AI architecture. He brings strong hands-on experience with AWS AI services, including SageMaker AI and SageMaker AI HyperPod, and leads the design and delivery of end-to-end AI solutions spanning model development, distributed training, and production-scale deployment. With deep experience in performance optimization and scalable ML architectures, Mayank partners with customers to translate complex business challenges into secure, high-impact, production-ready AI systems that drive measurable outcomes.

Deepthi Madamanchi is a Principal Technical Account Manager at AWS focused on AI Models, where she leads frontier AI segment through building and operating multi-thousand-node GPU clusters for foundation model training and inference. She specializes in distributed training, high-throughput networking, GPU fleet optimization, Amazon Bedrock adoption, helping them optimize performance, reliability, and cost efficiency from experimentation through production. In her free time, Deepthi explores functional health, experiments with new recipes, and travels with her family.

Dushyant Dubaria is a Senior Technical Account Manager on the AWS Frontier AI Startup team, where he supports frontier AI model builder companies deploying and operating large-scale GPU training infrastructure on Amazon SageMaker HyperPod and Amazon EKS. He specializes in distributed training orchestration, storage at petabyte scale (Amazon FSx for Lustre, Amazon S3), high-throughput networking, and operational resilience including cluster health monitoring, capacity planning, and proactive incident management for multi-thousand-node clusters. He helps organizations achieve reliable, high-performance ML workloads from initial cluster deployment through sustained production training. In his free time, he enjoys building automation tools, exploring new AI technologies, and playing cricket.

Shreyas Adiyodi is a Product Manager at AWS based out of Seattle. He is focused on enabling Gen AI model development on SageMaker HyperPod, partnering with customers to simplify cluster provisioning, accelerate foundation-model training, and strengthen security and compliance. Outside of work, he enjoys chess, MMA and watching movies.

Caching KMS data keys in multi-thread environments: Per-tenant encryption for event-driven systems at scale

Post Syndicated from Maria Gutovsky original https://aws.amazon.com/blogs/security/caching-kms-data-keys-in-multi-thread-environments-per-tenant-encryption-for-event-driven-systems-at-scale/

This post assumes familiarity with envelope encryption and the AWS Encryption SDK.

When your encryption system generates millions of duplicate API calls per hour, costs spiral and performance degrades. That’s exactly the challenge NICE Actimize faced while operating their global-scale, event-driven financial crime detection platform on Amazon Web Services (AWS).

NICE Actimize, a leading provider of financial crime, risk, and compliance solutions, processes millions of encrypted messages daily across hundreds of tenants. By rethinking how they cache encryption keys, they reduced their AWS Key Management Service (AWS KMS) costs by 77% while maintaining strict security guarantees and per-tenant encryption isolation.

In this post, we explore the cache stampede problem that emerges when envelope encryption meets high-concurrency, multi-tenant architectures. We walk through two solutions: the AWS-recommended hierarchical keyring pattern and a custom caching approach that NICE Actimize built for their regulated environment. These patterns apply to multi-tenant software as a service (SaaS) environments and high-throughput systems where per-tenant encryption generates significant KMS API volume.

Why per-tenant encryption matters

Financial services systems operate under strict regulatory requirements. You must encrypt data at rest and in transit. For multi-tenant SaaS providers, this requirement might go further: each tenant’s data must be encrypted with separate keys to provide complete cryptographic isolation. If one tenant’s key is compromised, no other tenant’s data is at risk.

Consider an enterprise SaaS environment built on an event-driven architecture using Amazon Managed Streaming for Apache Kafka (Amazon MSK), with many different databases for storing data and Amazon Simple Queue Service (Amazon SQS) for messaging. Messages flow continuously between producers and consumers, and each message must be encrypted with the correct tenant-specific key. At scale with millions of messages daily across hundreds of tenants, this creates a massive volume of encryption and decryption operations.

To handle this volume efficiently, the standard approach is envelope encryption: a two-tier model where an AWS KMS key encrypts short-lived data keys, and those data keys encrypt the actual data. Your application can encrypt large volumes of data locally without calling AWS KMS for every operation, reducing latency and costs.

The cache stampede problem

Envelope encryption reduces AWS KMS calls, but it doesn’t eliminate them. Each encrypt operation still requires a data key, either generated fresh using GenerateDataKey or retrieved from a cache, and each decrypt operation must unwrap an encrypted data key (EDK) by calling Decrypt. In high-throughput systems processing millions of messages, these calls add up quickly.

The AWS Encryption SDK provides a built-in solution for this: the CachingCryptoMaterialsManager. This component caches data encryption materials (data keys) locally, so your application can reuse them across multiple operations without calling AWS KMS each time. You configure a time-to-live (TTL), a maximum message-use limit, and a local cache, and the SDK handles the rest.

This approach works well under moderate load when you partition the cache by tenant AWS KMS key Amazon Resource Name (ARN) so that each tenant’s encryption materials remain cryptographically isolated. However, a critical problem emerges as concurrency scales to hundreds of threads processing millions of encrypted messages in parallel: the cache stampede, also known as the thundering herd problem.

How the stampede occurs

The CachingCryptoMaterialsManager caches the result of the SDK’s internal getMaterialsForEncrypt and decryptMaterials calls at the materials level. The cache stampede, however, happens at the KMS API call level. When a cached data key expires or a new, previously-unseen EDK arrives, the following sequence unfolds:

  1. On encrypt – data key explosion: Multiple threads simultaneously call encrypt() for the same tenant. Each thread finds the cache entry expired and independently calls GenerateDataKey against AWS KMS. Instead of one thread generating a data key while others wait, N threads create N distinct data keys. Each new data key produces a unique EDK, which inflates the EDK cardinality across the system.
  2. On decrypt – redundant unwrap calls: Those extra unique EDKs propagate downstream. When consumers later read encrypted records, each distinct EDK is a separate cache key. Multiple threads encountering the same EDK simultaneously each trigger an independent Decrypt call to AWS KMS because the cache has no coordination mechanism to make competing threads wait for a single in-flight request.
  3. Compounding effect: The encrypt-side stampede creates excess EDK cardinality, which degrades the decrypt-side cache hit ratio, which triggers more KMS calls, which drives up costs further. In the NICE Actimize case, this produced a ratio of 30% unique data keys to data records in DynamoDB tables, meaning nearly one in three records was encrypted with a different data key.

At enterprise SaaS scale, this compounding effect can generate millions of redundant AWS KMS GenerateDataKey and Decrypt calls per hour, even with the SDK’s built-in caching enabled. The following figure shows the pattern leading to a stampede.

Figure 1: Cache stampede – multiple threads independently calling AWS KMS for the same encrypted data key, creating duplicate requests

Figure 1: Cache stampede – multiple threads independently calling AWS KMS for the same encrypted data key, creating duplicate requests

The stampede follows this sequence on the encrypt side:

  1. Multiple threads call encrypt() for the same tenant concurrently.
  2. Each thread checks the CachingCryptoMaterialsManager and finds the cache entry expired.
  3. With no coordination mechanism, each thread independently calls GenerateDataKey.
  4. AWS KMS returns N distinct data keys (one per thread).
  5. Each data key produces a unique EDK, inflating cardinality across the system.

On the decrypt side, the inflated EDK cardinality compounds the problem:

  1. Consumer threads encounter unique EDKs that were never cached.
  2. Multiple threads hitting the same EDK simultaneously each trigger a separate Decrypt call. AWS KMS returns the same plaintext data key N times, doing redundant work.

Two paths forward

We evaluated two approaches to solve the cache stampede problem. Each fits different architectural requirements and regulatory constraints.

Option A: Hierarchical keyring with DynamoDB (AWS-recommended)

AWS addresses the cache stampede challenge through the hierarchical keyring pattern, which introduces an additional level of key hierarchy that significantly reduces how often cache stampedes occur.

In this architecture, branch keys serve as intermediate wrapping keys stored in a DynamoDB table. This DynamoDB table acts as a shared cache layer that coordinates across all instances in your distributed fleet.

Figure 2: Hierarchical keyring architecture – branch keys in DynamoDB coordinating across distributed instances

Figure 2: Hierarchical keyring architecture – branch keys in DynamoDB coordinating across distributed instances

The architecture (shown in Figure 2) works as follows:

  1. The application requests encryption through the hierarchical keyring.
  2. The keyring checks the local cache for the tenant’s branch key.
  3. On a cache miss, it queries the DynamoDB Key Store table for the active branch key.
  4. AWS KMS decrypts the branch key (this is the only KMS call in the flow).
  5. The decrypted branch key is returned to the keyring.
  6. The keyring stores the branch key in the local cache for subsequent requests.
  7. The keyring derives a unique wrapping key from the branch key and generates the data key locally.

The key insight is that the cache is thread-aware. When the cache expires, threads coordinate to make a single request to refresh the cache. Only a single thread is used to make a call to the branch key, rather than all the threads acting independently. Additionally, by adding an additional key into the key hierarchy, branch keys don’t live within AWS KMS. This means cache misses and the stampedes they trigger interact with the branch key, and don’t make as many calls to the AWS KMS service at the top of the hierarchy:

  • Without hierarchical keyrings: Your local cache needs to store all the data encryption keys, and has constant misses as new, unique data keys arrive with each encrypted message. A miss can trigger a stampede.
  • With hierarchical keyrings: The same branch key wraps thousands or millions of data keys. A cache miss only occurs when a branch key expires or is first requested, which happens orders of magnitude less frequently than without hierarchical keyrings.

The DynamoDB table acts as a coordination point. The first thread to request a missing branch key retrieves it from AWS KMS and stores it in DynamoDB (the Key Store table). Subsequent requests from instances in the fleet retrieve the cached branch key from DynamoDB instead of making duplicate AWS KMS calls.

Beyond reducing cache miss frequency, the hierarchical keyring provides built-in stampede protection within its local cache implementation. The SDK offers multiple cache types, and the Default cache, designed for heavily multi-threaded environments, prevents multiple threads from calling AWS KMS on cache expiry by notifying a single thread that the branch key materials entry is about to expire 10 seconds in advance. That one thread refreshes the cache while all other threads continue serving requests using the still-valid entry.

This solution integrates with the AWS Encryption SDK and requires minimal code changes to existing applications. For event-driven architectures processing encrypted Kafka streams, this approach reduces KMS call volume by orders of magnitude while preserving per-tenant cryptographic isolation.

Option B: Custom KMS client caching – Solving the stampede at the API layer

While the hierarchical keyring (Option A) addresses the stampede by reducing how often cache misses occur, there’s a complementary approach: eliminating the stampede at its source by caching KMS API responses directly, using atomic, single-flight cache loading that prevents concurrent threads from issuing duplicate calls. This is the path NICE Actimize took.

The IClientSupplier extension point in AWS Encryption SDK v3

In the AWS Encryption SDK v2, decorating the AWS KMS client on a per-request basis was possible through the RegionalClientSupplier interface, but it was an advanced and undocumented use case. Without explicit guidance or a supported pattern, caching strategies typically operated above the SDK layer, making it difficult to prevent duplicate KMS calls at their source. The AWS Encryption SDK v3 introduced the IClientSupplier interface, which the AwsKmsMrkMultiKeyring accepts at construction time. This interface is called by the SDK whenever it needs a KMS client for a given AWS Region, and you control what it returns, making it possible to insert a caching layer between the SDK and AWS KMS.

Architecture: A decorated KMS client with two Caffeine caches
The solution is a CachedKmsClient—a decorator that wraps the standard AWS SDK KmsClient and interposes two Caffeine LoadingCache instances between the application and AWS KMS:

Cache Key Value Purpose
GenerateDataKey cache GenerateDataKeyRequest (tenant KMS key ARN and key spec) GenerateDataKeyResponse (EDK and plaintext data key) Ensures encrypt operations on the same node reuse the same data key for a given tenant KMS key during the cache window
Decrypt cache DecryptRequest (EDK and key ARN) DecryptResponse (plaintext data key) Ensures decrypt operations for the same EDK share a single KMS call result

Both caches are configured with refreshAfterWrite (default: 1 hour, configurable), which means:

  • During the refresh window, concurrent threads receive the cached response instantly resulting in zero KMS calls.
  • When a cache entry expires, Caffeine’s LoadingCache.get() guarantees that exactly one thread executes the loader function (the actual KMS API call), while all other concurrent threads block and wait for that single result. This is the atomic, single-flight property that eliminates the stampede.

Security consideration: Caching plaintext data keys in memory means the keys exist in process memory for the duration of the cache TTL. The TTL acts as a security control: shorter TTLs reduce the window of exposure in the event of a memory dump, while longer TTLs reduce KMS call volume. Choose a TTL that balances your security requirements with your cost and performance goals. Key rotation at the KMS key level remains unaffected by the cache, because rotated keys produce new data keys on the next cache refresh.

Integration with the AWS Encryption SDK v3

The integration is minimal. The IClientSupplier AWS Lambda function returns a CachedKmsClient singleton for each AWS Region, this singleton is passed into the AwsKmsMrkMultiKeyring at keyring construction time. From that point forward, each GenerateDataKey and Decrypt call the SDK makes flows through the caching decorator transparently, with no changes to the encrypt or decrypt call sites.

The CachedKmsClient is a singleton per Region (managed using a ConcurrentHashMap), so all tenants on the same node share the same caching layer but their data keys remain fully isolated because the cache keys include the tenant-specific AWS KMS key ARN.

Why Caffeine?

Caffeine is a high-performance, near-optimal Java caching library well-suited for this pattern for several reasons:

  • Atomic loading: LoadingCache.get() guarantees that on a cache miss, only one thread executes the loader while others wait. This is the core property that eliminates the stampede.
  • refreshAfterWrite semantics: Unlike expireAfterWrite (which blocks all threads during refresh), refreshAfterWrite allows one thread to asynchronously reload the entry while other threads continue to serve the stale-but-valid cached value. This eliminates latency spikes during key rotation.
  • Observability: Cache eviction listeners and Micrometer metric counters can be wired in to track actual KMS call volume per tenant KMS key, enabling real-time cost monitoring.

Choosing between the two options

The hierarchical keyring with DynamoDB (Option A) is a production-ready, AWS-recommended solution that reduces stampede frequency by introducing longer-lived branch keys. It’s the best choice for most organizations. Particularly when starting fresh or when the operational overhead of an additional data store is acceptable.

NICE Actimize chose the custom caching approach (Option B) for a pragmatic reason: it avoided introducing a new infrastructure dependency into the encryption critical path. Their platform already operated at scale across hundreds of tenants, and adding a DynamoDB table as a key coordination layer would have meant taking on additional operational responsibility: provisioning, monitoring, backup, access control, and ensuring high availability for a component that sits directly in the encrypt/decrypt hot path. In a regulated financial services environment, each new stateful component in the security chain requires its own resilience planning, failure-mode analysis, and compliance review. The Caffeine cache used in Option B, by contrast, is an in-process library (a JAR on the classpath). It is stateless, requires no network calls, no provisioning and no operational overhead. It makes a lighter dependency than a managed cloud resource in the critical path. There is no shared state to lose, no additional infrastructure to protect, and no new failure mode beyond what already exists with AWS KMS itself. If a node restarts, the cache rebuilds on the next KMS call.

Results

By implementing a rotation policy with the optimized caching approach, NICE Actimize achieved the following results:

  • 77% reduction in AWS KMS costs – Eliminating millions of redundant API calls translated directly into significant cost savings.
  • Maintained strict per-tenant isolation – Per-tenant encryption isolation remained fully intact, with no compromise to their security posture.
  • Improved system performance – Removing the stampede of duplicate AWS KMS calls reduced latency and freed up system resources for core processing.
  • Simplified operations – A coordinated caching layer replaced fragmented, per-thread caching, reducing operational complexity.

Conclusion and next steps

The cache stampede problem compounds in multi-tenant encryption systems: excess data key generation on the encrypt side degrades cache hit ratios on the decrypt side, creating a feedback loop of redundant KMS calls. The AWS-recommended hierarchical keyring pattern with DynamoDB provides a production-ready solution that integrates with the AWS Encryption SDK with minimal code changes. For regulated environments requiring additional control, a custom caching approach can deliver similar results.

If you operate a multi-tenant SaaS platform or a high-throughput system with per-tenant encryption requirements, consider these patterns to optimize your encryption costs and performance.

To get started, explore the following resources:

If you have questions or feedback about this post, leave a comment in the Comments section.


Maria Gutovsky

Maria Gutovsky

Maria is a Solutions Architect at AWS, based in Tel Aviv, Israel. She is part of the Database and Analytics Technical Field Community. In her free time, you will probably find her building a new character for a Dungeons and Dragons campaign.

Hemmy Yona

Hemmy Yona

Hemmy is a Solutions Architect at AWS, based in Israel. With 20 years of experience in software development and group management, Hemmy is passionate about helping customers build innovative, scalable, and cost-effective solutions. Outside of work, you’ll find Hemmy enjoying sports and traveling with family.

Contributor

Special thanks to Devora Roth Goldshmidt, Head of X-Sight Architects at NICE Actimize, who made a significant contribution to this post.

Deliver Apache Kafka data to streaming tables for Apache Iceberg with Amazon MSK Express brokers

Post Syndicated from Shakhi Hali original https://aws.amazon.com/blogs/big-data/deliver-apache-kafka-data-to-streaming-tables-for-apache-iceberg-with-amazon-msk-express-brokers/

Today, we are announcing delivery to streaming tables on Apache Iceberg for Amazon Managed Streaming for Apache Kafka (Amazon MSK) Express brokers, a fully managed capability that continuously materializes your streaming data as queryable Apache Iceberg tables on Amazon S3 Tables, a capability of Amazon Simple Storage Service (Amazon S3). With delivery to streaming tables, you no longer need to deploy, scale, or maintain Kafka connectors, Flink jobs, or custom consumers to make your streaming data available for analytics. You select a Kafka topic, choose S3 Tables as your destination, and your data becomes a read-only Iceberg table queryable from Amazon Athena, Amazon Redshift, and Apache Spark within minutes. Delivery to streaming tables provides up to 60% cost savings compared to self-managed alternatives. It also reduces downstream query costs by up to 30% through optimized file sizing, without writing a single line of code or managing any infrastructure. Because this capability delivers to S3 Tables registered in AWS Glue Data Catalog, your tables are automatically discoverable through Glue Data Catalog Business Context and Semantic Search (preview). Data stewards can enrich streaming tables with business descriptions, glossary terms, and skill assets. AI agents can then discover and reason in real time using semantic search grounded in trusted business definitions rather than raw schema inference.

In addition to S3 Tables, you can deliver Amazon MSK streaming data to general purpose Amazon S3 buckets in source data format. Data delivery to general purpose Amazon S3 buckets enables workloads like archival, backup, or ML training data delivery. This provides a price-performant, serverless, and scalable way to deliver streaming data as-is to your general purpose Amazon S3 buckets.

Challenges with delivering streaming data to Apache Iceberg

Customers today face three critical challenges when integrating streaming data with Apache Iceberg. First, ease of use: customers must manage complex Kafka Connect deployments, handle frequent pipeline failures, maintain custom configurations, handle data format conversions, and manage pipeline infrastructure for data delivery. These operational tasks consume significant engineering time and introduce ongoing risk of downtime. Second, resiliency: without proper coordination, simultaneous writes from multiple high-throughput Kafka partitions can conflict with each other, leading to failed commits, data freshness delays, and performance issues. Streaming ingestion of high-volume data creates large numbers of small Parquet files in Iceberg tables, significantly degrading query performance and forcing a difficult trade-off between data freshness and query efficiency. Third, price performance can become a bottleneck to enriching your data lake with streaming data into. With delivery to streaming tables, pricing is predictable, and up to 60% lower than self managed Kafka deployments, lowering the barrier to getting real-time context to your data agents.

How delivery to streaming tables solves these challenges

Delivery to streaming tables is a native capability built directly into Amazon MSK Express brokers. It addresses each challenge directly: it eliminates operational complexity by removing the need to deploy, configure, or maintain pipeline infrastructure, you enable it with a few clicks. It provides built-in write coordination and exactly-once delivery semantics, resolving concurrent writer conflicts and supporting data integrity without manual intervention. And it performs intelligent inline compaction during ingestion, producing query-optimized Parquet files that eliminate the small-file problem while maintaining minute-level data freshness. The capability automatically scales to process gigabytes per second of throughput.

End-to-end managed streaming analytics architecture

With delivery to streaming tables, you now have a fully managed end-to-end real-time data architecture from data ingestion through storage to analytics. Your producers publish events to Amazon MSK Express brokers, which continuously deliver data as optimized Iceberg read-only tables in S3 Tables, registered automatically on AWS Glue Data Catalog. From there, you can query your streaming data using analytics engines like Amazon Athena, Amazon Redshift, Amazon EMR (Apache Spark), or Apache Flink . You can also let AI agents discover and reason over your data through Glue Data Catalog semantic search. This managed experience eliminates the intermediate infrastructure that customers previously assembled, no separate connector clusters, no compaction jobs, no custom consumers, replacing it with a single, serverless pipeline from stream to insight.

The following diagram illustrates this end-to-end architecture.

End-to-end streaming architecture from Amazon MSK Express brokers to Iceberg tables in Amazon S3 Tables, queried by Athena, Redshift, EMR, and Flink

Getting started

To get started, log into the Amazon MSK console, navigate to your Amazon MSK Express cluster, and enable delivery to streaming tables with a few clicks. Specify the Kafka topic you want to deliver, configure your schema settings using AWS Glue Schema Registry, and choose your destination. Destinations can be either fully managed Iceberg tables in S3 Tables or self-managed Iceberg tables in general purpose S3 buckets. Once enabled, delivery to streaming tables immediately begins materializing your Kafka data as queryable Iceberg tables in S3 with no further intervention required.

Additionally, you can use Amazon MSK APIs to programmatically set up, update, or delete delivery to streaming tables configurations for your Kafka topics. This allows teams to build agentic workflows and infrastructure-as-code patterns for teams managing configurations across multiple clusters and topics at scale.

Getting started with the streaming tables Agent Skill

The streaming tables Agent Skill provides AI-assisted guidance for setting up streaming tables integrations for your existing or new topics in Amazon MSK Express cluster. The skill helps you configure delivery to S3 Tables (Iceberg) or S3, including schema registry setup, IAM role configuration, and validation.

Installing as an Agent Skill

Agent Skills are discovered automatically by compatible tools through the SKILL.md file. Refer to the Agent Toolit for AWS Skill Installation Guide to install the managing-amazon-msk Agent Skill. We also recommend you install the AWS MCP Server in your developer tool of choice, which exposes tools for searching AWS documentation, blogs, and Skills dynamically at runtime. These capabilities make agents more accurate and powerful for AWS related development and operational tasks, and make skill discovery and installation more flexible. Refer to Setting up the AWS MCP Server for guidance on installing the AWS MCP Server in your environment.

For example:

aws configure agent-toolkit
aws agent-toolkit add-skill --skill-name managing-amazon-msk

To verify the installation, interact with the skill in your preferred tool.

To start delivering data from your Kafka topics to Apache Iceberg tables in real time, for example, prompt “Create me a streaming table on my MSK cluster for my events topic” to your agent of choice:

Agent chat showing the prompt to create a streaming table on an MSK cluster for the events topic

The agent will dynamically load the managing-amazon-msk skill, and start by gathering the available resources in your AWS account to use for the streaming tables integration. Once it gathers that data, it will confirm the resources to use or create, and create the integration:

Agent confirming the AWS resources to use and creating the streaming tables integration

After creating the integration, the agent will summarize the status and can then help with any other operational tasks with your data. For example, the agent can help you set up AWS Lake Formation permissions for you to query the data in S3 Tables with Athena, or configure your table maintenance behavior in S3 Tables:

Agent summarizing integration status and offering to set up Lake Formation permissions or configure S3 Tables maintenance

Conclusion

Delivery to streaming tables and general purpose S3 buckets is available in all AWS Regions where Amazon MSK Express brokers are available. To learn more about delivery to streaming tables, visit the documentation and pricing pages.


About the authors

Shakhi Hali

Shakhi Hali

Shakhi is a Product Manager for Amazon Managed Streaming for Apache Kafka. She works closely with AWS customers to understand their needs for real-time analytics and high throughput, low latency streaming workloads. Working backwards from their needs, she helps drive the Amazon MSK roadmap and deliver new innovations that help AWS customers focus on building novel streaming applications.

Mazrim Mehrtens

Mazrim Mehrtens

Mazrim is a Sr. Specialist Solutions Architect for messaging and streaming workloads. Mazrim works with customers to build and support systems that process and analyze terabytes of streaming data in real time, run enterprise Machine Learning pipelines, and create systems to share data across teams seamlessly with varying data toolsets and software stacks.

Huyam Hasan

Huyam Hasan

Huyam is a Solutions Architect II at AWS, based in Austin, TX, with a passion for data and analytics solutions and customer success. She works with enterprise customers across travel, gaming, and hospitality to design and build modern, secure, and scalable data and streaming architectures, with a focus on real-time analytics that help them achieve their business outcomes.

Zero Copy access to Apache Iceberg tables in Amazon S3 from Salesforce Data 360 using the Iceberg REST endpoint from AWS Glue Data Catalog

Post Syndicated from Avijit Goswami original https://aws.amazon.com/blogs/big-data/zero-copy-access-to-apache-iceberg-tables-in-amazon-s3-from-salesforce-data-360-using-the-iceberg-rest-endpoint-from-aws-glue-data-catalog/

Companies increasingly need to query and analyze data across platforms without the cost and complexity of moving it. Salesforce and AWS have collaborated to make this possible by providing Zero Copy access to Apache Iceberg tables stored in Amazon Simple Storage Service (Amazon S3) directly from Salesforce Data 360, using the Iceberg REST endpoint from AWS Glue Data Catalog with data access managed by AWS Lake Formation. This integration helps customers federate their Amazon S3 data lakes with Data 360, preserving data governance, freshness, and business semantics without replication.

Zero Copy file federation plays an important role in activating applications and experiences. By removing the need to physically move or copy data, and connecting to data at the storage level, it addresses key challenges including:

  • Cost efficiency – Reduce storage duplication costs and minimize the compute resources required for data pipelines.
  • High scale – Access data with near-native performance at scale through in-Region access.
  • Enhanced agility – Access and analyze data in real time, accelerating time-to-insight and supporting faster response to evolving business needs.
  • Streamlined operations – Remove the complexity of building and maintaining intricate data pipelines, clearing up valuable data engineering resources.

In this post, we demonstrate how AWS and Salesforce customers can access their enterprise data lakes on AWS from Data 360 using Zero Copy file federation.

What is Data 360?

Data 360 is the real-time data engine that activates trusted context across the entire Salesforce platform. It connects all your enterprise data — data warehouses, data lakes, third-party signals, and more — to the business context, logic, and governance that already live in Salesforce, without moving or copying it. With Zero Copy federation, your teams and AI agents always operate from a complete, current, and trusted picture of your business in the moment it’s needed. It serves as the essential system of context for Agentforce, enabling agents to reliably get real work done.

What is Apache Iceberg?

Apache Iceberg is a high-performance, open table format for huge analytic datasets that brings the reliability and simplicity of SQL tables to big data. It’s a thriving open source project under the Apache Software Foundation. Data engineers use Apache Iceberg because it’s fast, efficient, and reliable at any scale and keeps records of how datasets change over time. Apache Iceberg offers integrations with popular data processing frameworks such as Apache Spark, Apache Flink, Apache Hive, Presto, and more.

Why Amazon S3 for Apache Iceberg data lakes?

Amazon S3 is regarded as the best place to build data lakes because of its durability, availability, scalability, security, compliance, and audit capabilities, and its ability to integrate with a broad portfolio of AWS and third-party tools for data ingestion and processing. Apache Iceberg was designed and built to interact with Amazon S3, and provides support for many Amazon S3 features as listed in the Iceberg documentation.

What is Zero Copy file federation?

File federation, also termed catalog federation, uses the Data Catalog to communicate with remote catalog systems to discover catalog objects and to authorize access to their data in Amazon S3. When you query a remote Iceberg table, the Data Catalog discovers the latest table information in the remote catalog at query runtime, getting the table’s Amazon S3 location, current schema, and partition information. Your analytics engine then uses this information to access Iceberg data files directly from Amazon S3, and Lake Formation manages access to the table and data by vending scoped credentials to the table data stored in Amazon S3. This approach avoids metadata and data duplication while providing real-time access to remote Iceberg tables through your preferred AWS analytics engines.

Solution overview

Apache Iceberg file federation lets Data 360 directly query data stored in Amazon S3 without copying or moving the data. This Zero Copy approach provides several benefits:

  • Real-time access to Amazon S3 data from Salesforce.
  • Reduced data movement and storage costs.
  • Simplified data architecture.
  • Improved data freshness.

The following diagram illustrates the architecture of the integration between Data 360 and Amazon S3 using Apache Iceberg file federation.

Key components:

  1. Amazon S3 stores the source data in Apache Iceberg format.
  2. AWS Glue Data Catalog maintains the metadata for Iceberg tables.
  3. AWS Glue Iceberg REST endpoint provides RESTful access to Iceberg tables.
  4. AWS Lake Formation manages metadata and underlying data access for Amazon S3-based data lakes.
  5. Data 360 processes and analyzes the data.
  6. Apache Iceberg connector provides direct access to query Amazon S3 data from Salesforce.

Walkthrough

The following walkthrough shows you how to set up Zero Copy file federation.

Prerequisites

Before you begin, you need the following:

Configure your AWS environment

Set up an Amazon S3 bucket and Iceberg table

Sign in as the data lake admin and complete the following steps:

  1. Open the Amazon S3 console.
  2. Choose Create bucket to create a bucket.
  3. For Bucket type, choose General purpose, provide a Bucket name, and choose Create bucket.
  4. In the bucket, create two prefixes by choosing Create folder.
  5. Name the prefixes athena_iceberg and athena_results.
  6. Inside the athena_iceberg prefix, create another prefix named customer_iceberg.

Create an Iceberg table using Athena

  1. Open the Amazon Athena console.
  2. Choose Query your data in Athena console, then choose Launch query editor.
  3. In Athena, choose Edit settings.
  4. Set s3://<your-bucket-name>/athena_results/ as the Location of query result, then choose Save. Replace <your-bucket-name> with your bucket name.
  5. Choose Editor to return to the query editor page.
  6. To create the database, copy the following query into the query editor and choose Run. You need to be in the Athena Query Editor to run the following commands.
    create database iceberg_db;

  7. To create the Iceberg table, copy the following query into the query editor, replace <s3 bucket location> with your Amazon S3 bucket location hosting the Iceberg table, and choose Run.
    CREATE TABLE iceberg_db.churn (
        state string,
        account_length int,
        area_code string,
        phone string,
        intl_plan string,
        vmail_plan string,
        vmail_message int,
        day_mins double,
        day_calls int,
        day_charge double,
        eve_mins double,
        eve_calls int,
        eve_charge double,
        night_mins double,
        night_calls int,
        night_charge double,
        intl_mins double,
        intl_calls int,
        intl_charge double,
        custserv_calls int,
        churn boolean)
    LOCATION 's3://<s3 bucket location>/iceberg/churn'
    TBLPROPERTIES (
        'table_type'='iceberg',
        'compression_level'='3',
        'format'='PARQUET',
        'write_compression'='ZSTD'
    );

  8. Insert some records into the table.
    -- Sample data insert for "iceberg_db"."churn"
    -- Execute this in the Athena console
    INSERT INTO "iceberg_db"."churn" VALUES
    ('KS', 128, '415', '382-4657', 'no', 'yes', 25, 265.1, 110, 45.07, 197.4, 99, 16.78, 244.7, 91, 11.01, 10.0, 3, 2.70, 1, false),
    ('OH', 107, '415', '371-7191', 'no', 'yes', 26, 161.6, 123, 27.47, 195.5, 103, 16.62, 254.4, 103, 11.45, 13.7, 3, 3.70, 1, false),
    ('NJ', 137, '415', '358-1921', 'no', 'no', 0, 243.4, 114, 41.38, 121.2, 110, 10.30, 162.6, 104, 7.32, 12.2, 5, 3.29, 0, false),
    ('OH', 84, '408', '375-9999', 'yes', 'no', 0, 299.4, 71, 50.90, 61.9, 88, 5.26, 196.9, 89, 8.86, 6.6, 7, 1.78, 2, false),
    ('OK', 75, '415', '330-6626', 'yes', 'no', 0, 166.7, 113, 28.34, 148.3, 122, 12.61, 186.9, 121, 8.41, 10.1, 3, 2.73, 3, false),
    ('AL', 118, '510', '391-8027', 'yes', 'no', 0, 223.4, 98, 37.98, 220.6, 101, 18.75, 203.9, 118, 9.18, 6.3, 6, 1.70, 0, false),
    ('MA', 121, '510', '355-9993', 'no', 'yes', 24, 218.2, 88, 37.09, 348.5, 108, 29.62, 212.6, 118, 9.57, 7.5, 7, 2.03, 3, false),
    ('MO', 147, '415', '329-9001', 'yes', 'no', 0, 157.0, 79, 26.69, 103.1, 94, 8.76, 211.8, 96, 9.53, 7.1, 4, 1.92, 0, false),
    ('WV', 141, '415', '330-8173', 'yes', 'yes', 37, 258.6, 84, 43.96, 222.0, 111, 18.87, 326.4, 97, 14.69, 11.2, 5, 3.02, 0, false),
    ('IN', 65, '415', '329-6603', 'no', 'no', 0, 129.1, 137, 21.95, 228.5, 83, 19.42, 208.8, 111, 9.40, 12.7, 6, 3.43, 4, true),
    ('RI', 74, '415', '344-9230', 'no', 'no', 0, 187.7, 127, 31.91, 163.4, 148, 13.89, 196.0, 94, 8.82, 9.1, 5, 2.46, 0, false),
    ('IA', 168, '408', '363-1107', 'no', 'no', 0, 275.8, 90, 46.89, 230.0, 73, 19.55, 191.3, 57, 8.61, 9.9, 3, 2.67, 4, true),
    ('MT', 95, '510', '394-8006', 'no', 'no', 0, 113.2, 96, 19.24, 269.9, 107, 22.94, 229.1, 87, 10.31, 7.1, 4, 1.92, 1, false),
    ('NY', 62, '415', '371-5765', 'no', 'no', 0, 236.5, 127, 40.21, 145.3, 101, 12.35, 225.0, 103, 10.13, 12.0, 1, 3.24, 5, true),
    ('TX', 109, '408', '356-2992', 'no', 'yes', 33, 190.7, 114, 32.42, 218.2, 111, 18.55, 156.5, 122, 7.04, 11.6, 5, 3.13, 1, false),
    ('CA', 155, '510', '328-8230', 'no', 'no', 0, 197.3, 78, 33.54, 160.2, 86, 13.62, 280.1, 90, 12.60, 8.8, 2, 2.38, 2, false),
    ('WA', 132, '415', '382-1011', 'yes', 'no', 0, 302.7, 67, 51.46, 212.0, 105, 18.02, 265.5, 82, 11.95, 10.3, 4, 2.78, 3, true),
    ('FL', 88, '408', '344-5678', 'no', 'yes', 18, 145.3, 95, 24.70, 187.6, 92, 15.95, 198.2, 108, 8.92, 9.4, 3, 2.54, 0, false),
    ('CO', 201, '510', '367-4321', 'no', 'no', 0, 312.5, 142, 53.13, 178.9, 76, 15.21, 145.7, 95, 6.56, 14.2, 8, 3.83, 6, true),
    ('GA', 56, '415', '390-2244', 'no', 'yes', 12, 178.4, 101, 30.33, 205.1, 119, 17.43, 230.8, 100, 10.39, 8.0, 2, 2.16, 1, false);

Register the bucket with Lake Formation in Lake Formation mode

To use Lake Formation permissions for access control to the churn table, you must register the location. To do that, complete the following actions:

  1. Open the AWS Lake Formation console.
  2. In the navigation pane under Administration, choose Data lake locations.
  3. Choose Register location and enter the following information:
    1. For S3 URI, enter s3://<s3 bucket location>/iceberg/churn. Replace <s3 bucket location> with your Amazon S3 bucket location hosting the Iceberg table.
    2. For IAM role, choose the user-defined IAM role that you created in the prerequisites.
    3. For Permission mode, choose Lake Formation.
  4. Choose Register location.

Enable third-party integration in Lake Formation

From the Lake Formation console, enable full table access for external engines.

  1. Open the AWS Lake Formation console.
  2. On the left pane, expand the Administration section.
  3. Choose Application integration settings and select Allow external engines to access data in Amazon S3 locations with full table access.
  4. Choose Save.

Application integration settings page in the Lake Formation console with full table access enabled for external engines

Set up an IAM user for third-party access

  1. Open the IAM console.
  2. From the left navigation menu, choose Policies, then choose Create policy. Choose JSON and paste the following policy:
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Sid": "VisualEditor0",
                "Effect": "Allow",
                "Action": "lakeformation:GetDataAccess",
                "Resource": "*"
            }
        ]
    }

  3. Choose next, provide a name for the policy, and choose Create policy.
  4. From the left navigation menu, choose Users, then choose Create user.
  5. For username, enter data_cloud_user, choose next, and choose Attach policies directly.
  6. Choose AWSGlueServiceRole and the policy that you created in step 3. Choose next and Create user.
  7. Choose the user, then choose Security credentials to create an access key.
  8. Scroll down and choose Create access key, choose Applications running outside AWS, and choose Create access key.
  9. Copy the access key and secret access key, and save them securely. You need these to configure the connector in Data 360.

Set up Lake Formation resource permissions for third-party data access

  1. Open the Lake Formation console.
  2. From the left navigation under Data Catalog, choose Databases, then choose the athena_iceberg_db database.
  3. From the Actions menu, choose Permissions, Grant.
  4. In Principals, choose IAM users and roles, and from the menu choose data_cloud_user, which you just created in IAM.
  5. Scroll down to grant permissions by choosing All tables, then choose Select and Describe permissions for the tables.
  6. Choose Grant to apply the permissions.

Set up Apache Iceberg file federation in Data 360

Create and configure the connection

  1. Navigate to Salesforce Setup. For instructions, see Set Up the AWS Glue Data Catalog Connection.
  2. In Data Cloud, choose Setup, then choose Data Cloud Setup.
    Data Cloud Setup page in Salesforce showing options to configure connections
  3. Under External Integrations, choose Other Connectors.
  4. Choose New.
  5. On the Source tab, choose AWS Glue Data Catalog, then choose Next.
    New connector page in Salesforce Data Cloud with AWS Glue Data Catalog selected as the source
  6. Complete the following information shown in the following screen:
    1. In the Authentication Details section, enter the AWS access key ID and AWS secret access key for the IAM user. Make sure that the IAM user has a policy that grants the user read-only access to AWS Glue Data Catalog. Use Lake Formation to configure storage credential vending. This approach is for AWS Glue Data Catalog to vend temporary credentials at run time so that Data 360 can access the underlying storage bucket.
    2. For Catalog URL, enter the URL of AWS Glue Data Catalog. See Connecting to the Data Catalog by using AWS Glue Iceberg REST endpoint.
    3. For Catalog ID, enter the 12-digit AWS account ID linked to AWS Glue Data Catalog.
    4. For Signing Region, enter the host AWS Region where AWS Glue Data Catalog is located.
    5. For Signing Service, enter glue. Data 360 requires the Signing Service, in addition to the AWS access key ID, secret access key, and Signing Region, to sign requests to AWS Glue Data Catalog by using AWS Signature Version 4.
    6. Test the connection and check for the success message.
    7. Save the connection details.

    AWS Glue Data Catalog connection configuration form in Salesforce Data Cloud showing authentication details, catalog URL, catalog ID, signing Region, and signing service fields

  7. After the configuration is complete and saved, the new AWS Glue Data Catalog connection shows up with “Active” status in the Connectors screen.Connectors screen in Salesforce Data Cloud showing the new AWS Glue Data Catalog connection with Active status

Create and configure the data stream

  1. In Data Cloud, on the Data Streams tab, choose New.
  2. Under Other Sources, choose the AWS Glue Data Catalog source, then choose Next.
  3. From the menus, choose the connection that you just set up, choose a database in your AWS Glue catalog where you have an Iceberg table, choose the table that you want to stream, and choose Next.Data stream configuration page showing AWS Glue Data Catalog source with connection, database, and Iceberg table selection menus
  4. Enter the object name and object API name. For more information, see Data Lake Object Naming Standards.
  5. Choose the category to specify the type of data to ingest. For more information, see Category.
  6. Choose a primary key to uniquely identify the incoming records. For more information, see Primary Key.
  7. Choose the source fields you want to ingest, then choose Next. Fields with convertible data types are listed under Supported Fields.Source fields selection page showing supported fields for the Iceberg table data stream
  8. Choose the relevant data space. Choose “Default” if you don’t have any other data space provisioned in your org. For more information, see Data Spaces.
  9. Choose Deploy.
    Data stream deployment confirmation page in Salesforce Data Cloud
  10. After the setup is complete, the new data stream appears in your Data Cloud environment.
    Data Cloud environment showing the newly deployed data stream for the Iceberg table
  11. The data stream is ready. You can now go to the Data Explorer in your Data Cloud environment and start viewing the Iceberg tables that reside in your external AWS account.Data Explorer in Salesforce Data Cloud showing Iceberg tables from the external AWS account

Best practices and considerations

  • Use IAM roles with least-privilege access. Grant only the specific permissions each service or user needs.
  • Implement appropriate Amazon S3 bucket policies. Define bucket-level policies that restrict access by AWS account, VPC endpoint, or IP range.
  • Monitor access patterns. Enable Amazon S3 server access logging or AWS CloudTrail data events to track who reads from and writes to your table buckets.
  • Optimize Iceberg table partitioning. Choose partition keys that align with your most common query filters.
  • Consider data access patterns. Design your table layout around how data is actually queried.
  • Implement lifecycle policies for Amazon S3 objects. Configure Amazon S3 lifecycle rules to transition older data files to other storage classes.
  • Use appropriate Iceberg file compaction strategies. Run compaction regularly to merge small files produced by streaming or frequent batch appends.
  • Monitor data transfer costs. Track cross-Region and internet egress charges using AWS Cost Explorer as applicable.

Clean up

After you finish testing, clean up all the resources in your AWS account that you created (including the Amazon S3 bucket, Athena tables, and other AWS services) to avoid recurring costs.

Conclusion

By implementing Apache Iceberg file federation between Data 360 and Amazon S3, you can create a more efficient and streamlined data architecture. This solution gives you real-time access to Amazon S3 data while using the analytics capabilities of Data 360. As businesses continue to prioritize data-driven decision-making, Zero Copy data sharing plays an important role in unlocking the full potential of customer data across platforms.

To learn more, review the following resources:


About the authors

Avijit Goswami

Avijit Goswami

Avijit is a principal specialist solutions architect at AWS specializing in data and analytics. He helps customers design and implement robust data lake solutions. Outside the office, you can find Avijit exploring new trails, discovering new destinations, cheering on his favorite teams, enjoying music, or testing out new recipes in the kitchen.

Srividya Parthasarathy

Srividya Parthasarathy

Srividya is a Senior Big Data Architect on the AWS Lake Formation team. She works with the product team and customers to build robust features and solutions for their analytical data platform. She enjoys building data mesh solutions and sharing them with the community.

Pratik Das

Pratik Das

Pratik is a Senior Product Manager with AWS Lake Formation. He is passionate about all things data and works with customers to understand their requirements and build delightful experiences. He has a background in building data-driven solutions and machine learning systems

Bill Tarr

Bill Tarr

From software builder to architecture, Bill has 20+ years of experience shaping best-in-class SaaS technology strategies for organizations from startup to enterprise. He’s also an AWS SaaS community leader and a producer of the “Building SaaS on AWS” show on twitch.com/aws, as well as an experienced public speaker with experience at top tier AWS events such as re:Invent, and publisher of SaaS best practices.

Build an AI-powered real estate assistant on WhatsApp using Strands Agents SDK and AWS End User Messaging

Post Syndicated from Ruchikka Chaudhary original https://aws.amazon.com/blogs/messaging-and-targeting/build-an-ai-powered-real-estate-assistant-on-whatsapp-using-strands-agents-sdk-and-aws-end-user-messaging/

Most real estate websites collect form submissions and route them to sales teams who respond hours or days later. Customers who expect immediate answers often move on. This post shows how to close that gap with a WhatsApp assistant that responds instantly. We show you how to build a real estate assistant powered by AI that delivers property discovery, home loan pre-approval, and site visit booking entirely within WhatsApp. The solution uses the Strands Agents SDK to orchestrate specialized AI agents on Amazon Bedrock, with AWS End User Messaging Social for WhatsApp integration. The serverless backend runs on AWS Lambda and Amazon DynamoDB.

Prerequisites

You need an AWS account with permissions for AWS CloudFormation, Lambda, Amazon Simple Notification Service (Amazon SNS), Amazon Bedrock, and DynamoDB. You also need a WhatsApp Business account integrated with AWS End User Messaging. For instructions to locate your WhatsApp phone number ID, see View a phone number’s ID in AWS End User Messaging Social.

For more information about how to set up WhatsApp using AWS End User Messaging Social, refer to Automate workflows with WhatsApp using AWS End User Messaging Social.

AWS Serverless Application Model (AWS SAM) CLI is required to deploy the demo solution. For installation instructions, see the AWS SAM CLI installation guide.

Overview of solution

The architecture uses four AI agents built with the Strands Agents SDK. Each agent handles a specific task: identity verification, credit scoring, fraud detection, or property valuation. The agents use Strands SDK decorators to access external data sources. The agents run on Amazon Bedrock with the Nova Lite model and are deployed to AWS Lambda using the official Strands Agents Lambda Layer. AWS End User Messaging Social handles WhatsApp Business API integration, publishing incoming messages to Amazon SNS for routing. The webhook handler Lambda function processes these events and invokes the supervisor agent. The supervisor agent orchestrates the conversation flow, maintains session state in Amazon DynamoDB, and sends rich interactive messages back to customers on WhatsApp.

For this post, we use a demo landing page to simulate the “Enquire Now” button on a real estate website. In a production scenario, you can add this integration point to any existing website. The only requirement is a WhatsApp click-to-chat link that pre-fills the initial message with the property details.

The following diagram illustrates the solution architecture:

Solution architecture diagram: WhatsApp messages flow through AWS End User Messaging Social and Amazon SNS to a Lambda webhook handler and supervisor agent that orchestrates four Strands agents on Amazon Bedrock with session state in Amazon DynamoDB.

Strands Agents SDK — multi-agent pipeline

The Strands Agents SDK is an open source framework from AWS for building AI agents. Each agent gets a system prompt and tools. The agent then decides when to use those tools based on what the user asks.

This solution uses four specialized agents, each with its own tools:

  • Identity Agent – uses the verify_identity tool to validate the customer’s tax identification number.
  • Credit Scoring Agent – uses check_credit_score and get_loan_offers tools to assess creditworthiness and generate lending offers.
  • Fraud Detection Agent – uses check_fraud_risk to evaluate application risk.
  • Property Valuation Agent – uses validate_property to check regulatory registration and market value.

The following example shows how to define agents using the Strands @tool decorator pattern. Each tool is region-agnostic by design. You adapt the implementation for your local tax authority, credit bureau, and property registry.

from strands import Agent, tool
from strands.models.bedrock import BedrockModel

MODEL_ID = "amazon.nova-lite-v1:0"

def get_model():
    return BedrockModel(model_id=MODEL_ID, region_name="us-east-1")

@tool
def verify_identity(tax_id: str) -> dict:
    """Verify customer identity using their tax identification number.
    Adapt for your region: PAN (India), SSN (US), NIN (UK), TFN (Australia)."""
    # Call your regional tax authority API here
    return {"tax_id": tax_id, "valid": True,
            "holder_name": "Customer", "status": "Active"}

@tool
def check_credit_score(tax_id: str) -> dict:
    """Fetch customer credit score from a credit bureau.
    Adapt for your region: CIBIL (India), FICO (US), Experian (Global)."""
    # Call your regional credit bureau API here
    return {"credit_score": 782, "risk_category": "Low"}

@tool
def get_loan_offers(property_price: int, credit_score: int) -> dict:
    """Get mortgage offers from partner lending institutions.
    Adapt for your region's banks and lending regulations."""
    # Call your partner bank APIs here
    return {"offers": [...]}

@tool
def validate_property(name: str, registration_id: str, price: int) -> dict:
    """Validate property registration with the local regulatory authority.
    Adapt for your region: RERA (India), Land Registry (UK), MLS (US)."""
    # Call your regional property registry API here
    return {"registration_valid": True, "investment_rating": "good"}

You then orchestrate the agents in a pipeline:

def run_full_pipeline(tax_id, phone, project):
    # Agent 1: Identity Verification
    agent = Agent(
        model=get_model(),
        system_prompt="You are an Identity Verification Agent. "
                      "Use verify_identity to check the customer's tax ID.",
        tools=[verify_identity],
        callback_handler=None
    )
    identity = agent(f"Verify tax ID: {tax_id}")

    # Agent 2: Credit Scoring + Loan Offers
    agent = Agent(
        model=get_model(),
        system_prompt="You are a Credit Scoring Agent. "
                      "Use check_credit_score then get_loan_offers.",
        tools=[check_credit_score, get_loan_offers],
        callback_handler=None
    )
    credit = agent(f"Check credit for {tax_id}, "
                   f"get offers for price {project['price']}")

    # Agent 3: Fraud Detection
    # Agent 4: Property Valuation
    # ... similar pattern
    return consolidated_results

AWS End User Messaging Social

AWS End User Messaging Social handles WhatsApp Business API integration. Incoming messages arrive as events. Outgoing messages, including text, buttons, lists, and location cards, go through the SendWhatsAppMessage API.

Message routing with Amazon SNS

An SNS topic receives events from AWS End User Messaging Social whenever customers send WhatsApp messages.

Webhook handler – AWS Lambda

The webhook handler Lambda function parses the EUM Social event envelope, extracts the WhatsApp message payload, and routes it based on message type.

Supervisor agent – AWS Lambda with Strands Agents

The supervisor agent orchestrates the full conversation flow. It maintains session state in Amazon DynamoDB and sends rich WhatsApp messages back to the customer. When the customer submits their identification, the supervisor invokes the Strands agent pipeline, which runs four agents sequentially on Amazon Bedrock.
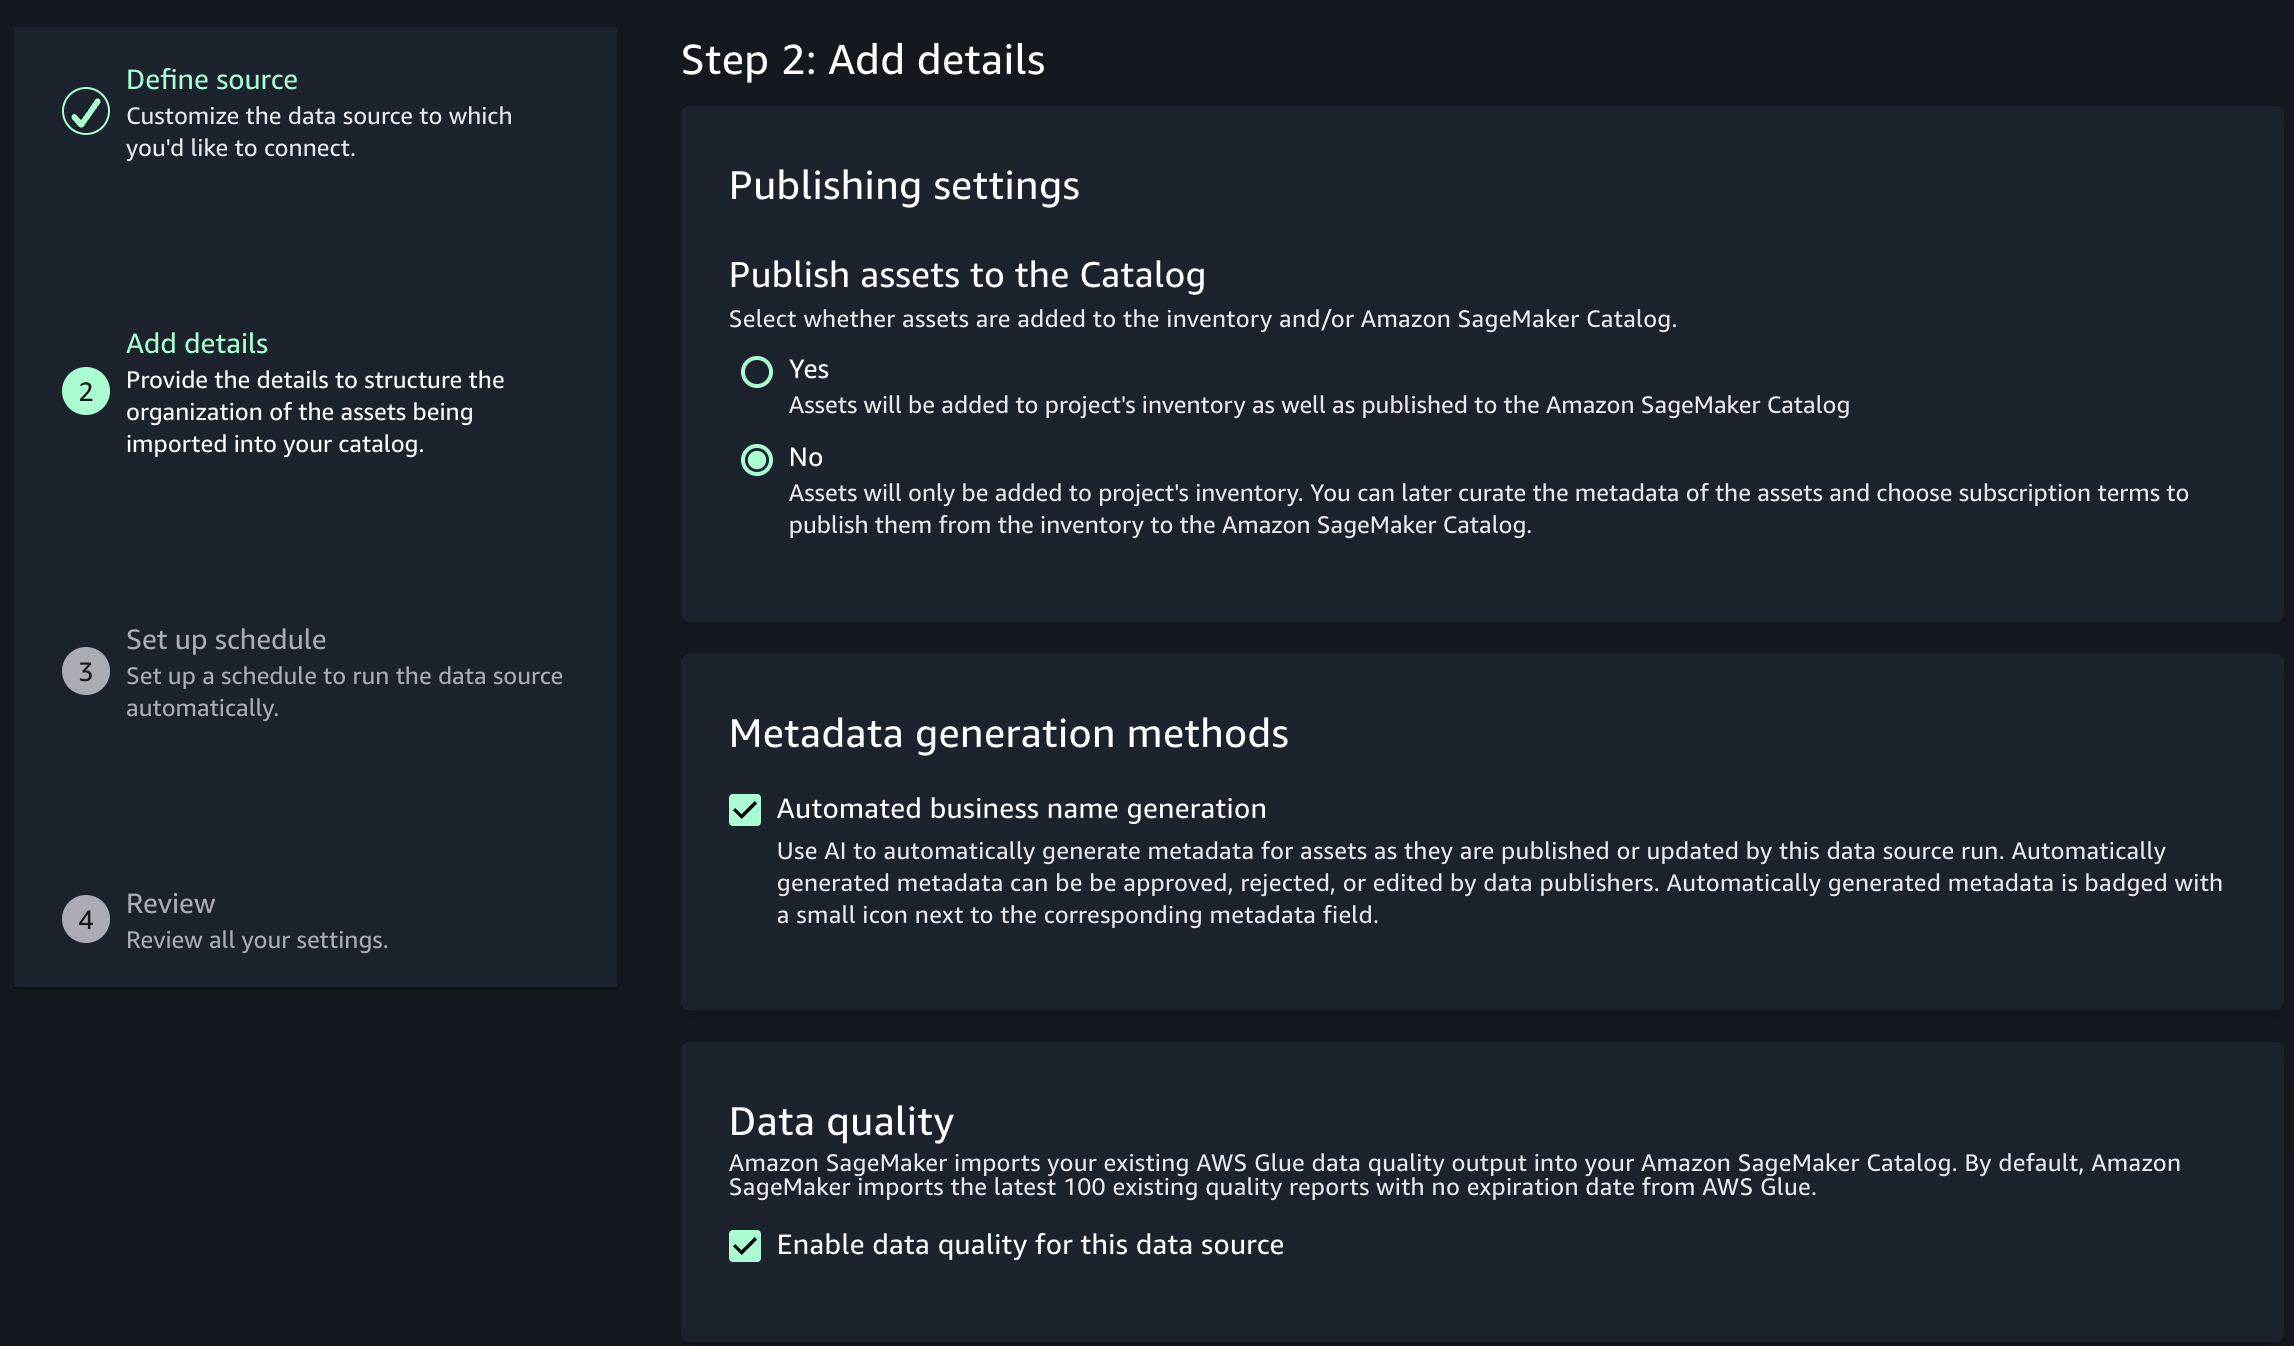
The supervisor sends interactive WhatsApp messages using the EUM Social API:

def send_list(self, to_phone, body, button_text, sections):
    payload = {
        "messaging_product": "whatsapp",
        "to": to_phone,
        "type": "interactive",
        "interactive": {
            "type": "list",
            "body": {"text": body},
            "action": {
                "button": button_text,
                "sections": sections
            }
        }
    }
    response = self.client.send_whatsapp_message(
        originationPhoneNumberId=self.phone_number_id,
        message=json.dumps(payload).encode('utf-8'),
        metaApiVersion='v21.0'
    )

Lambda Layer for Strands Agents

The Strands Agents SDK provides an official Lambda Layer that includes all required dependencies pre-built for the Lambda runtime.

Session state – Amazon DynamoDB

Two DynamoDB tables store conversation state. The sessions table tracks the full conversation state machine (INITIATED, AWAITING_PROJECT_SELECT, AWAITING_ACTION, AWAITING_ID, LOAN_APPROVED, VISIT_CONFIRMED), with a 30-minute TTL.

Conversation flow

The customer journey unfolds across four steps in WhatsApp.

Step 1: Property discovery

When the customer sends the initial message, the supervisor agent sends a welcome message followed by an interactive list picker showing properties grouped by developer. The list picker uses WhatsApp’s native interactive message format.

Step 2: Property detail with action buttons

When the customer selects a property, the supervisor sends a rich detail card with key highlights, regulatory registration, and three action buttons:

eum.send_buttons(phone, body, [
    {"id": "check_loan", "title": "Check Loan"},
    {"id": "book_visit", "title": "Book Site Visit"},
    {"id": "talk_sales", "title": "Talk to Sales"}
])

Step 3: Loan pre-approval with Strands Agents

When the customer chooses Check Loan and submits their tax identification number, the supervisor invokes the Strands agent pipeline. Four agents run sequentially on Amazon Bedrock, each using its specialized tools. The following log output shows the pipeline in action:

Running Strands agent pipeline for ID: ABCD****
Identity agent: True
Credit agent: score=782, offers=3
Fraud agent: low
Property agent: good

The customer receives a loan approval card with offers from multiple lending institutions, each with personalized interest rates based on the credit score returned by the credit agent. The full pipeline typically runs in under 10 seconds.

Step 4: Site visit booking

The customer selects a time slot from an interactive list picker and receives a confirmation with relationship manager details and a location card.

Demo implementation: India real estate market

This demo uses India-specific implementations: PAN validation for identity, CIBIL scores for credit (300-900 range), example bank offers with EMI in Rupees, RERA registration validation, and free cab pickup for site visits.

To adapt this solution for another region, you replace the tool implementations with calls to your local tax authority, credit bureau, lending institutions, and property registry. The agent architecture, WhatsApp integration, and conversation flow remain unchanged.

Deployment

To deploy the demo solution, run the following commands:

git clone https://github.com/aws-samples/sample-ai-powered-real-estate-agent.git
cd sample-ai-powered-real-estate-agent
./deploy.sh --env=demo \
    --phone-number-id <your-phone-number-id> \
    --business-number +14155552671 \
    --region us-east-1

After deployment, in the AWS End User Messaging Social console, route incoming messages for your phone number ID to the SNS topic demo-whatshome-incoming-messages created by the stack.
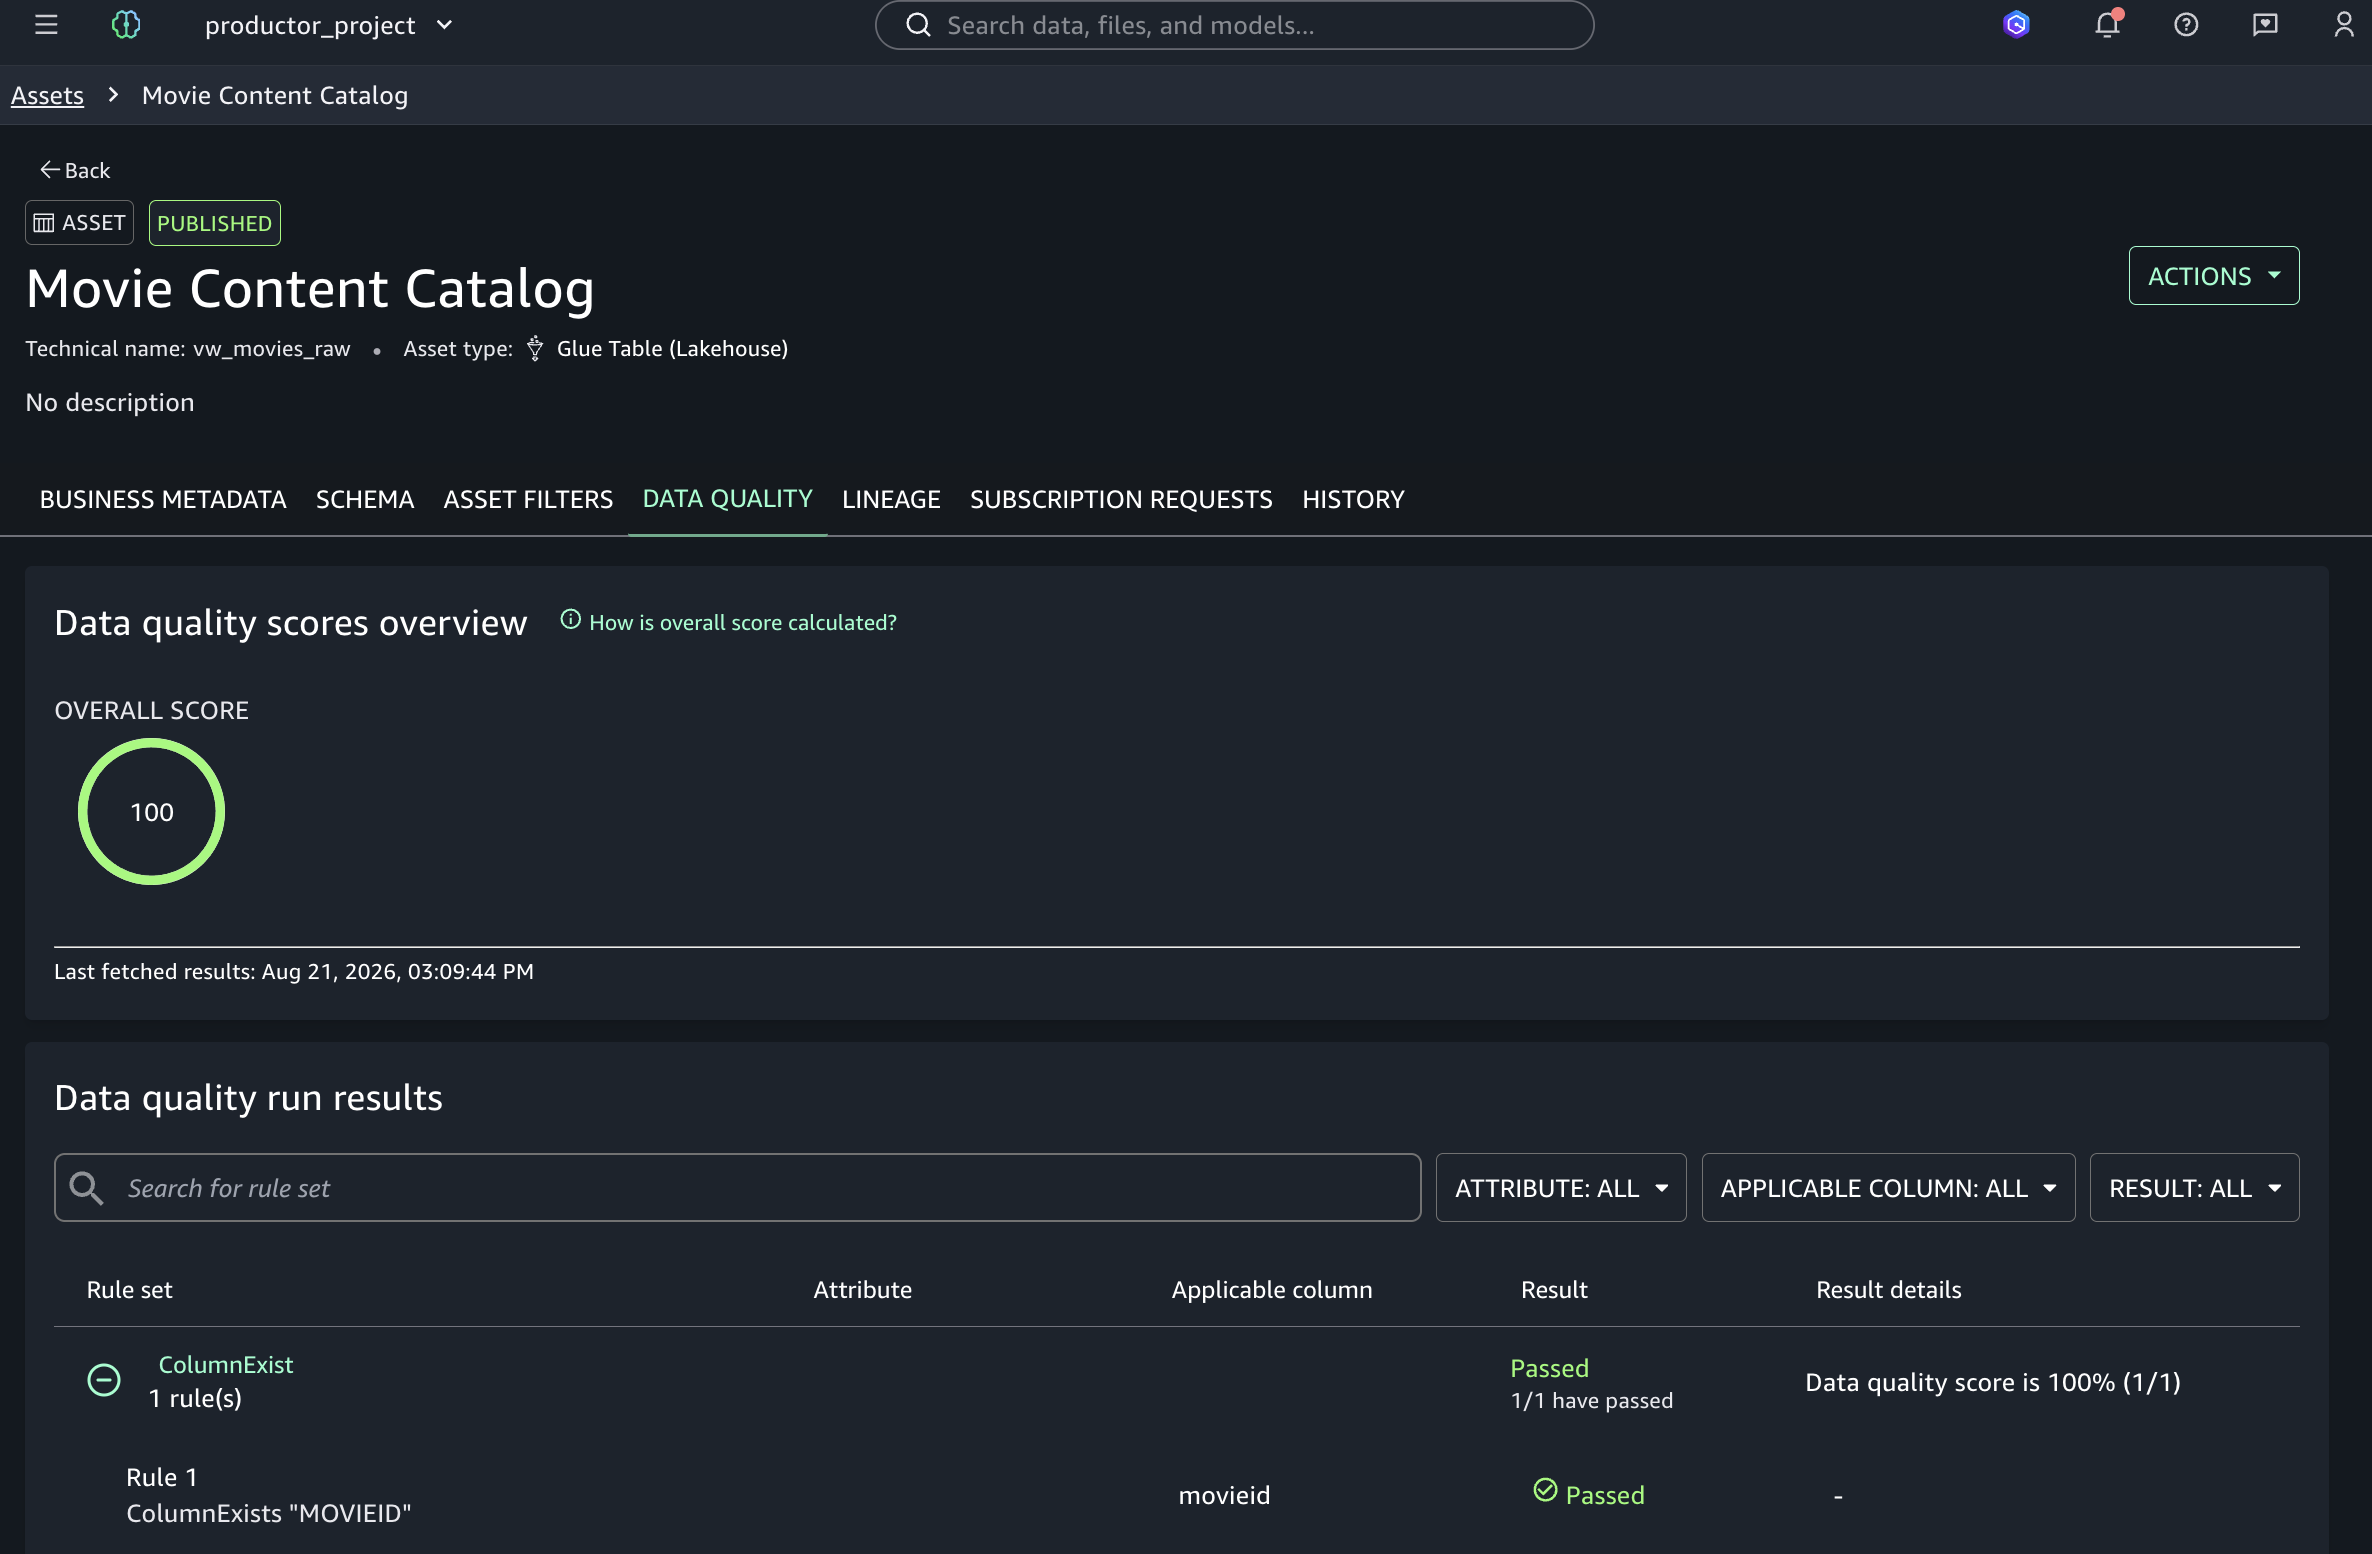
Test the solution

open demo/real-estate-landing.html

Select Enquire Now on any property card. WhatsApp opens at the configured business number with a prefilled message. Send the message and finish the loan pre-approval flow on WhatsApp.

Sample conversation

The following images show how a customer interacts with the real estate AI assistant.

WhatsApp screen showing the customer’s prefilled enquiry message and the AI assistant’s welcome reply with a list picker of available properties.

The customer lands on WhatsApp with a predefined message from the website, and the AI assistant greets them with a welcome message.

WhatsApp screen showing a property detail card with three action buttons: Check Loan, Book Site Visit, and Talk to Sales.

The customer selects the Check Loan option for one of the properties listed.


WhatsApp screen showing a loan approval card with offers from SBI, HDFC, and LIC Housing Finance, each with personalized interest rates.

The agents are invoked to verify the customer details and provide loan quotations.

WhatsApp screen showing a site visit confirmation with the assigned relationship manager’s details and a pinned location card.

The customer books a site visit after selecting a suitable time slot.

Clean up

To avoid ongoing charges, delete the resources you created during this walkthrough:

sam delete --stack-name whatshome-demo --region us-east-1

Deleting the CloudFormation stack removes the Lambda functions, DynamoDB tables, Amazon SNS topics, Amazon Simple Queue Service (Amazon SQS) queue, AWS Key Management Service (AWS KMS) key, and AWS Identity and Access Management (IAM) roles. If you deployed the demo landing page to Amazon Simple Storage Service (Amazon S3) and Amazon CloudFront, delete those resources separately.

Conclusion

You can combine the Strands Agents SDK, Amazon Bedrock, AWS End User Messaging Social, and Lambda to build an end-to-end WhatsApp assistant. The multi-agent architecture has specialized agents for identity verification, credit scoring, fraud detection, and property valuation. This decomposition shows how you can break complex business workflows into focused AI agents that collaborate to deliver instant results.

The same pattern works for banking loan applications, insurance claims, healthcare appointments, and ecommerce order tracking.

To get started, see the AWS End User Messaging Social documentation and the Strands Agents SDK on GitHub.


About the authors

Getting your SMS short code production-ready with AWS End User Messaging

Post Syndicated from Harshvardhan Chunawala original https://aws.amazon.com/blogs/messaging-and-targeting/getting-your-sms-short-code-production-ready-with-aws-end-user-messaging/

Getting your Short Message Service (SMS) short code production-ready requires you to configure the Amazon Web Services (AWS) infrastructure that controls how your messages are sent, monitored, and protected. You have provisioned your short code, and it is active on carrier networks. In this post, we walk through that setup using AWS End User Messaging SMS, covering 12 configuration steps from compliance through phased traffic migration. Total estimated time is 2 to 4 hours of configuration plus 1 to 3 business days for limit increase approvals.mess

The guide to SMS short codes with AWS End User Messaging covers the application and registration process up through provisioning. This post picks up from that point and provides an operational readiness walkthrough that takes you from “Active” status to confidently sending your first production message, including a final validation step to confirm readiness.

The following diagram shows the end-to-end message flow and event routing architecture covered in this walkthrough.

End-to-end SMS short code architecture showing message flow from sender through AWS End User Messaging SMS to carriers and recipient handsets, with event routing to Amazon CloudWatch, Amazon Simple Notification Service (Amazon SNS), and Amazon Data Firehose destinations

Prerequisites

You need the following to follow along with this walkthrough:

  1. An AWS account with access to the AWS End User Messaging SMS console.
  2. A short code with Active status in the AWS Management Console (carrier provisioning finished).
  3. Permissions to create AWS Identity and Access Management (IAM) roles, Amazon CloudWatch Log Groups, and Amazon Simple Notification Service (Amazon SNS) topics.
  4. AWS Command Line Interface (AWS CLI) v2 or an AWS SDK installed and configured.
  5. Your approved registration documentation, including the service name, keyword responses, and message templates submitted to carriers.

Step 1: Verify your short code is active and delivering

Navigate to the AWS End User Messaging SMS console, choose Phone numbers, and locate your provisioned short code. Confirm that the status shows Active, then send a test message to a phone number you control using the SendTextMessage API or the console test feature. Verify delivery on your handset.

Carrier-side activation can take up to 24 to 48 hours to fully propagate across all networks after provisioning finishes. If the console shows Active but your test message does not arrive, submit a support case so the team can verify propagation status with the carrier.

You can also verify using the AWS CLI:

aws pinpoint-sms-voice-v2 send-text-message \
    --destination-phone-number "+15555550100" \
    --origination-identity "12345" \
    --message-body "Test message from short code" \
    --message-type TRANSACTIONAL \
    --configuration-set-name "prod-otp-shortcode"
# Replace +15555550100 with your test phone number, 12345 with your short
# code, and prod-otp-shortcode with your configuration set name from Step 3.

Step 2: Configure keywords and verify message compliance

US carriers require every short code to respond to HELP and STOP keywords. You defined these during your registration, and this step confirms they are configured correctly in your account.

In the SMS console, choose Phone numbers, select your short code, and choose the Keywords tab. Verify that STOP returns the opt-out response you submitted during registration, and that HELP returns your support contact response (which must include a phone number or email). Add any custom keywords your use case requires, such as YES for double opt-in confirmation flows. You can manage keywords programmatically using the PutKeyword API.

To add or update a keyword programmatically:

aws pinpoint-sms-voice-v2 put-keyword \
    --origination-identity "12345" \
    --keyword "YES" \
    --keyword-message "You have confirmed your subscription to Acme Health Alerts. Msg&data rates may apply. Reply STOP to opt out." \
    --keyword-action AUTOMATIC_RESPONSE
# Replace 12345 with your short code, YES with your custom keyword, and the
# keyword-message text with your approved response.

To verify your current keyword configuration:

aws pinpoint-sms-voice-v2 describe-keywords \
    --origination-identity "12345"
# Replace 12345 with your short code.

Beyond keyword configuration, carrier compliance does not end at registration approval. The content you send in production must stay aligned with what carriers reviewed and approved. Here is what to keep consistent.

Use the exact brand or program name from your approved registration across all keyword responses, confirmation messages, and outbound templates. If carriers approved your registration under “Acme Health Alerts,” every message your short code sends should reference that name. Mixing variations creates inconsistencies that auditors flag during reviews. For example, do not use the company name in one message and the product name in another.

Your HELP, STOP, and confirmation responses must match the templates submitted during registration. Do not add or remove opt-out language, change frequency disclosures, or alter customer care contact details post-approval without updating the registration through a support case. If your organization operates multiple domains, use the domain documented in the registration. For example, you might have one domain for the application and another for marketing. Carrier reviewers cross-reference message content, opt-in screenshots, and privacy policy URLs with what was submitted.

Humans conduct carrier reviews, and message content that is concise and limited to the essentials is reviewed consistently. All messages must remain under 160 characters.

Step 3: Create a configuration set with event destinations

A configuration set controls where your SMS delivery events are streamed and which event types are captured. Without one, you are limited to the basic events that AWS End User Messaging SMS sends to Amazon EventBridge by default. These default events omit recipient details and full carrier response context.

Create a configuration set with a descriptive name such as prod-otp-shortcode or marketing-sc-us. Then create at least one event destination. The three main options are Amazon CloudWatch Logs (for operational monitoring and alarming), Amazon SNS (for real-time event fanout to downstream systems), and Amazon Data Firehose (for durable archival and analytics).

Amazon Data Firehose typically delivers to an Amazon Simple Storage Service (Amazon S3) bucket, where you can query delivery history using Amazon Athena for compliance audits or delivery pattern analysis.

# Create the configuration set
aws pinpoint-sms-voice-v2 create-configuration-set \
    --configuration-set-name "prod-otp-shortcode"

# Add a CloudWatch Logs event destination
aws pinpoint-sms-voice-v2 create-event-destination \
    --configuration-set-name "prod-otp-shortcode" \
    --event-destination-name "otp-delivery-logs" \
    --matching-event-types TEXT_DELIVERED TEXT_FAILED TEXT_QUEUED TEXT_CARRIER_UNREACHABLE TEXT_TTL_EXPIRED \
    --cloud-watch-logs-destination '{
        "IamRoleArn": "arn:aws:iam::123456789012:role/SMSEventsToCloudWatch",
        "LogGroupArn": "arn:aws:logs:us-east-1:123456789012:log-group:/aws/sms/prod-otp-shortcode"
    }'
# Replace prod-otp-shortcode with your configuration set name, otp-delivery-logs
# with a descriptive destination name, and the ARN values with your IAM role ARN
# (must have logs:PutLogEvents permission) and CloudWatch Log Group ARN.

Important: When sending messages with SendTextMessage, always specify your ConfigurationSetName parameter so events route to the appropriate destination.

Required event types

Event type Description
TEXT_DELIVERED Message successfully delivered to recipient handset.
TEXT_FAILED Message delivery failed.
TEXT_QUEUED Message accepted and queued for delivery.
TEXT_CARRIER_UNREACHABLE Carrier network unreachable.
TEXT_TTL_EXPIRED Message expired before delivery.

For a detailed walkthrough of configuration sets including multi-tenant architectures, see How to send SMS using configuration sets with AWS End User Messaging.

Step 4: Create a phone pool and associate your short code

A pool is a logical container that groups origination identities and controls routing behavior. Creating one gives you deterministic control over which number sends your messages and how opt-outs are enforced.

# Create the pool
aws pinpoint-sms-voice-v2 create-pool \
    --origination-identity "12345" \
    --iso-country-code "US" \
    --message-type TRANSACTIONAL

# Disable shared routes so only your short code is used
aws pinpoint-sms-voice-v2 update-pool \
    --pool-id "pool-1234567890abcdef0" \
    --shared-routes-enabled false
# Replace 12345 with your short code, US with your destination country code,
# and pool-1234567890abcdef0 with the Pool ID returned by create-pool.

Configuration parameters

Parameter Recommended value Rationale
Pool name us-otp-pool Descriptive, environment-prefixed.
SharedRoutesEnabled False Prevents fallback to shared routes; only your short code is used.
Opt-out list Associate one Manages opt-out state per use case.
IsoCountryCode US Restricts to destination country your short code serves.

If you operate multiple use cases on separate short codes, create a dedicated pool for each. For example, use one short code for one-time password (OTP) traffic and another for transactional notifications. This isolation means a recipient opting out of marketing messages does not lose access to authentication codes.

Step 5: Request your throughput increase

Short codes start at a default of 100 messages per second (MPS). If your production volume will exceed this, request an increase before your launch date rather than after traffic is flowing.

Create a case in the AWS Support Center, choose Service limit increase, then choose End User Messaging SMS. Provide your short code phone number, requested MPS, use case description, and expected peak volume. Allow 1 to 3 business days for processing.

To estimate your required MPS:

Required MPS = (Peak hourly volume / 3,600) x 2

Short codes support scaling to thousands of MPS, so start with a value that covers your expected peak and request further increases as traffic grows.

Step 6: Request a spending limit increase

AWS accounts have a default monthly SMS spending limit. To keep delivery uninterrupted at your expected volume, request an increase that accommodates your projected monthly spend before you begin sending.

Create a support case under Service limit increase > End User Messaging SMS > Account Spend Threshold. Provide your estimated monthly spend, use case description, and website URL.

For details, see Requesting increases to your monthly SMS spending quota.

Step 7: Restrict destination countries

If your short code serves a single country (US-only, for example), restrict sending to that country. This protects your account from artificially inflated traffic (SMS pumping). In pumping attacks, messages are routed to international premium-rate numbers, generating significant charges.

In the SMS console, navigate to Account settings, then choose Countries and keep only the countries you intend to send to. The pool-level IsoCountryCode restriction from Step 4 provides an additional enforcement layer at the sending path. Combining account-level country restrictions with pool-level country codes gives you two independent controls that both must be satisfied before a message is sent internationally.

For a detailed walkthrough on SMS fraud prevention controls, see Defending against SMS pumping: new AWS features to help combat artificially inflated traffic.

Step 8: Set up monitoring and alarms

With event destinations configured in Step 3, build proactive alerting that surfaces delivery trends before they affect your end users.

Alarm Metric / Source Threshold
Delivery success rate CloudWatch SMS metrics Alert when below 95%.
Spend threshold CloudWatch billing metric Alert at 80% of monthly limit.
Delivery failures Amazon EventBridge rule on TEXT_FAILED Route to Amazon SNS topic or AWS Lambda.
Carrier unreachable Amazon EventBridge rule on TEXT_CARRIER_UNREACHABLE Route to Amazon SNS topic or AWS Lambda.

Build a CloudWatch dashboard showing messages sent per minute, success versus failure breakdown, and spend accumulation over time.

You can also configure Amazon EventBridge to notify you of registration status changes. AWS End User Messaging SMS publishes events for statuses including REQUIRES_UPDATES, REVIEWING, and PROVISIONING, which is useful if a carrier requests changes during a proactive audit after your short code is already active.

For metric details, see Monitoring SMS activity with Amazon CloudWatch.

Step 9: Track OTP verification success (if applicable)

If your short code delivers OTP or two-factor authentication (2FA) codes, track end-to-end verification success in addition to carrier delivery receipts. A “delivered” status at the carrier level does not confirm the end user received and entered the code.

Tracking verification rates gives you insight into latency patterns when codes expire before arrival, geographic delivery trends, and opportunities to improve conversion. Some use cases involve asynchronous processing where several minutes of computation occur before the SMS is sent. For these, measure the full round-trip from the triggering action to message delivery. This separates application-side latency from carrier-side delivery latency.

For implementation guidance, see Track OTP success with AWS End User Messaging SMS feedback.
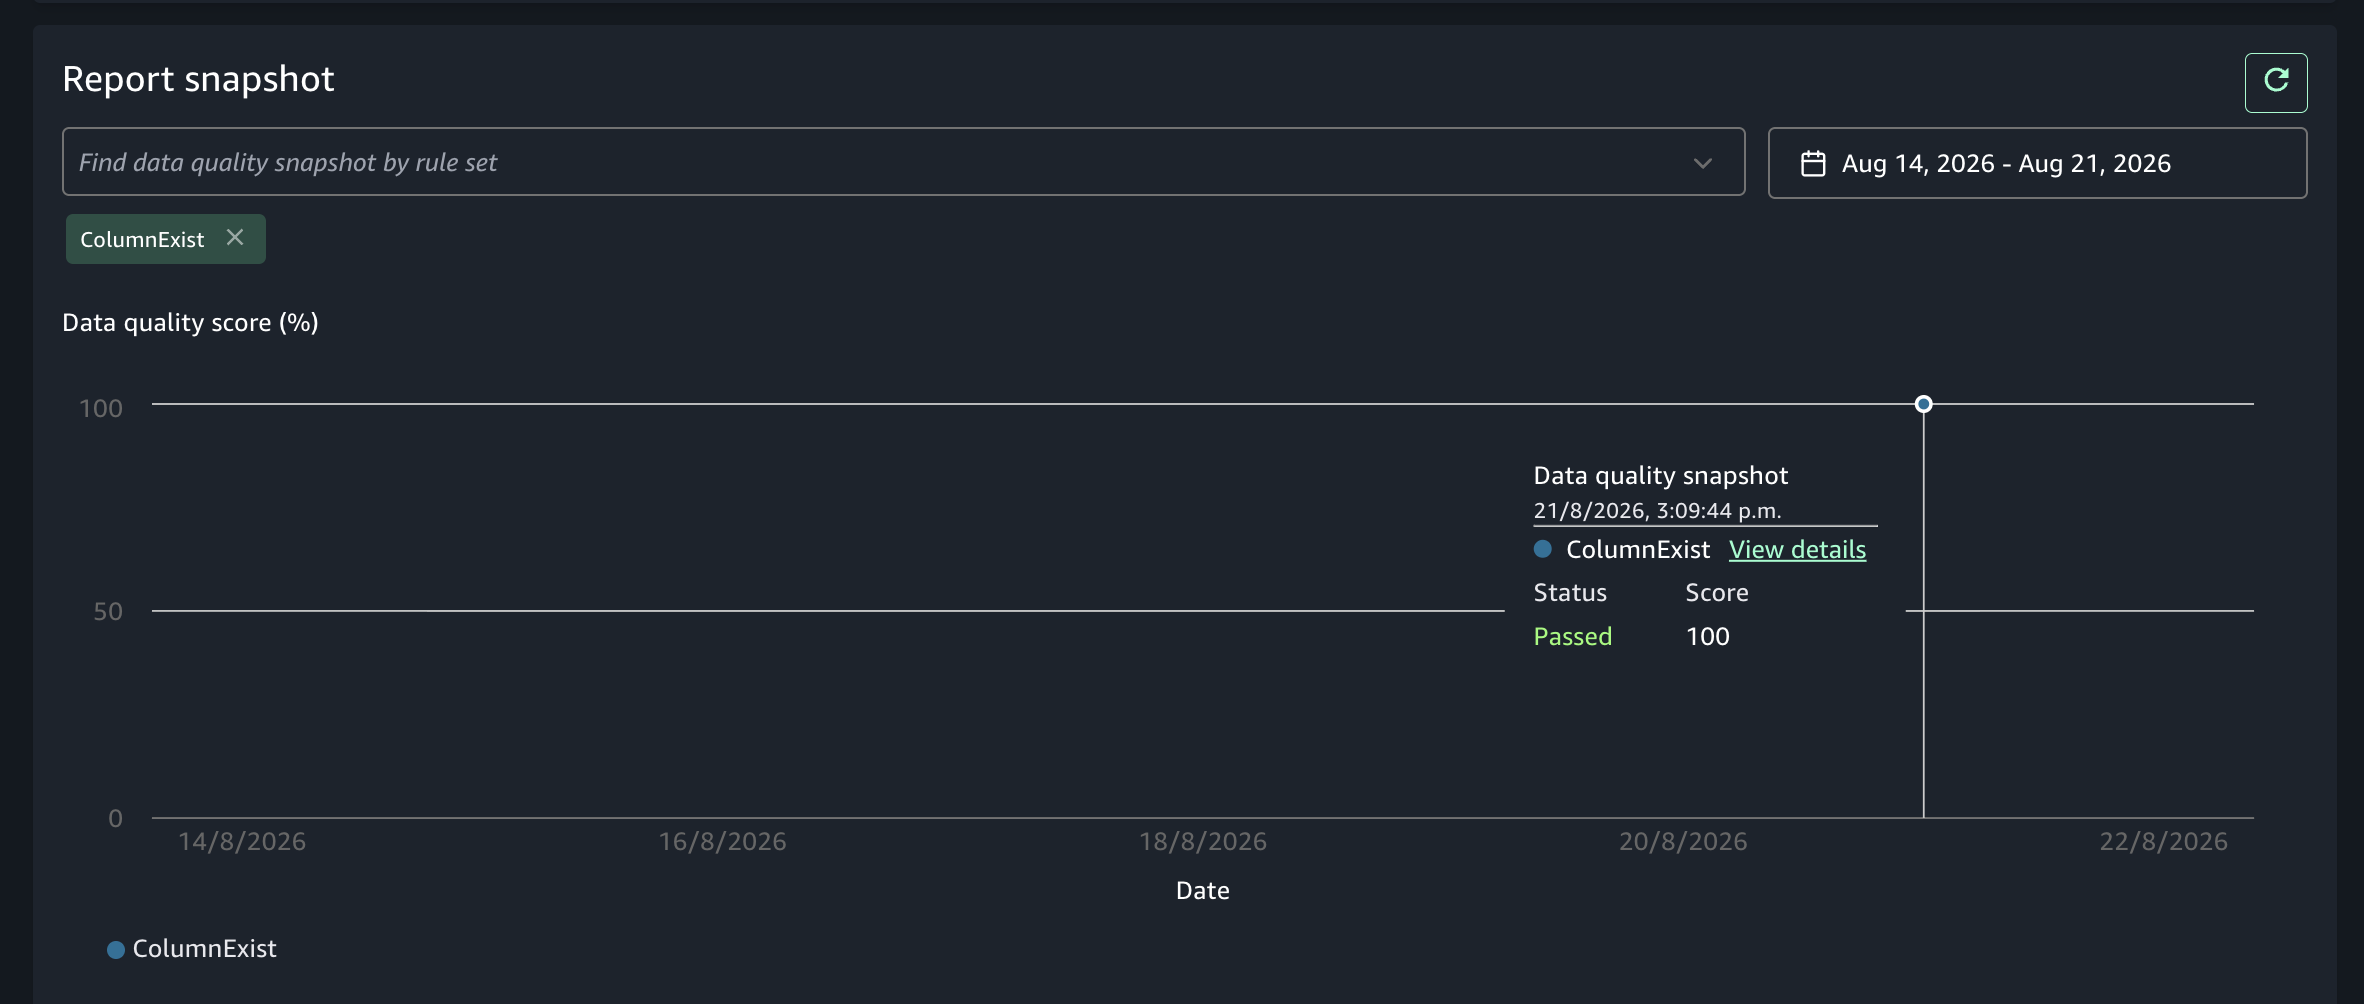
Step 10: Set up cost visibility

SMS costs include AWS charges plus per-message carrier surcharges. Setting up cost visibility from day one lets you track spend trends, catch anomalies early, and optimize over time.
Start by activating AWS Cost Explorer and creating a cost allocation tag for your SMS workload. Then configure an AWS Budget with threshold alerts. For example, you might notify at 80% of projected monthly spend. This gives you advance warning of unexpected cost increases, whether from traffic spikes, retry loops, or blocked-country leakage.

Step 11: Plan your traffic migration

A phased rollout validates delivery performance at each stage before you increase volume.

Start with a canary phase (Day 1 to 3) where you route 5 to 10% of traffic to the short code and monitor delivery rates, latency, and event logs. Move to a ramp phase (Day 3 to 7) at 50%, validating throughput and carrier-level delivery across your recipient base. Finish the full migration (Day 7+) at 100%. Decommission your previous origination identity only after confirming stability for at least 48 hours.

Step 12: Validate production readiness and send

Before declaring your short code production-ready, run through the following validation checks:

  1. Confirm your CloudWatch dashboard shows events flowing for TEXT_DELIVERED and TEXT_FAILED (from Step 3).
  2. Send a test message that triggers your STOP keyword. Verify the correct opt-out response is returned and the phone number appears in your opt-out list.
  3. Send a test message that triggers your HELP keyword. Verify the response matches your approved registration.
  4. Check your MPS quota in the support case response (from Step 5). Confirm it matches or exceeds your calculated peak.
  5. Review your country restrictions (from Step 7). Attempt to send a message to a blocked country and confirm it is rejected.
  6. Verify your CloudWatch alarm fires by temporarily lowering the threshold, or by checking that the alarm state is not INSUFFICIENT_DATA.

After all six checks pass, you are ready to begin your phased migration (Step 11) and scale to full production traffic. At this point, your short code is configured, monitored, compliant, and protected.

Automate with a validation script

You can use an AI coding assistant such as Kiro to generate a validation script tailored to your environment. Try a prompt like: “Write a boto3 script that validates my SMS short code is production-ready by checking Active status, HELP/STOP keywords, configuration set existence, and pool association using the pinpoint-sms-voice-v2 client.”

Refine the prompt with specifics from the following reference implementation, such as exact API names, filter parameters, and output format, to match your requirements.

The following script is an example of what that output looks like:

import boto3
import sys

SHORT_CODE = "12345"  # TODO: Replace with your short code (e.g., "67890")
POOL_ID = "pool-1234567890abcdef0"  # TODO: Replace with your pool ID from Step 4
CONFIG_SET_NAME = "prod-otp-shortcode"  # TODO: Replace with your configuration set name from Step 3

client = boto3.client("pinpoint-sms-voice-v2")

# Note: For accounts with many resources, implement NextToken pagination
# on describe_* calls. This script assumes results fit in a single page.


def check_short_code_active():
    """Step 1: Verify short code is Active."""
    response = client.describe_phone_numbers(
        Filters=[
            {"Name": "status", "Values": ["ACTIVE"]},
            {"Name": "number-type", "Values": ["SHORT_CODE"]}
        ]
    )
    numbers = [
        n for n in response["PhoneNumbers"]
        if n["PhoneNumber"] == SHORT_CODE
    ]
    assert len(numbers) > 0, f"Short code {SHORT_CODE} not found or not Active"
    print(f"[PASS] Short code {SHORT_CODE} is Active")


def check_keywords_configured():
    """Step 2: Verify HELP and STOP keywords exist."""
    response = client.describe_keywords(OriginationIdentity=SHORT_CODE)
    keyword_names = [kw["Keyword"].upper() for kw in response["Keywords"]]
    assert "STOP" in keyword_names, "STOP keyword not configured"
    assert "HELP" in keyword_names, "HELP keyword not configured"
    print("[PASS] HELP and STOP keywords configured")


def check_configuration_set():
    """Step 3: Verify configuration set exists."""
    response = client.describe_configuration_sets(
        ConfigurationSetNames=[CONFIG_SET_NAME]
    )
    assert len(response["ConfigurationSets"]) > 0, f"Configuration set {CONFIG_SET_NAME} not found"
    print(f"[PASS] Configuration set '{CONFIG_SET_NAME}' exists")


def check_pool_association():
    """Step 4: Verify pool exists and short code is associated to it."""
    response = client.describe_pools(PoolIds=[POOL_ID])
    assert len(response["Pools"]) > 0, f"Pool {POOL_ID} not found"

    # Verify short code is associated to the pool
    assoc_response = client.list_pool_origination_identities(PoolId=POOL_ID)
    identities = [
        oi["OriginationIdentity"]
        for oi in assoc_response["OriginationIdentities"]
    ]
    assert any(SHORT_CODE in oi for oi in identities), \
        f"Short code {SHORT_CODE} not associated with pool {POOL_ID}"
    print(f"[PASS] Pool '{POOL_ID}' exists and short code is associated")


if __name__ == "__main__":
    checks = [
        check_short_code_active,
        check_keywords_configured,
        check_configuration_set,
        check_pool_association,
    ]
    for check in checks:
        try:
            check()
        except Exception as e:
            print(f"[FAIL] {check.__doc__} - {e}")
            sys.exit(1)
    print("\nAll validation checks passed. Ready for production traffic.")

Cleaning up

If you created test resources while following this walkthrough, you can delete them through the AWS End User Messaging SMS console or with the API to avoid confusion with your production configuration. This includes a test configuration set, test pool, or test event destinations used for validation. Do not delete your production configuration set, pool, or keyword settings.

If you requested a test-level MPS increase or spending limit for validation, update these to your production values through a new support case before going live.

Quick reference checklist

Step Action Key API / Service
1 Verify short code is Active and test delivery SendTextMessage
2 Configure keywords and verify message compliance PutKeyword
3 Create configuration set with event destinations CreateConfigurationSet
4 Create pool and associate short code CreatePool, AssociateOriginationIdentity
5 Request MPS increase for expected throughput AWS Support
6 Request spending limit increase AWS Support
7 Restrict destination countries Console / UpdateAccount
8 Set up CloudWatch alarms and dashboards Amazon CloudWatch
9 Track OTP verification success (if applicable) SMS Feedback events
10 Set up cost visibility AWS Cost Explorer, AWS Budgets
11 Plan phased traffic migration Application-level routing
12 Validate production readiness and send All of the preceding

Conclusion

In this post, we walked through how to configure a newly provisioned SMS short code for production use with AWS End User Messaging SMS. The 12 steps cover keyword verification, message compliance, event monitoring, throughput planning, country restrictions, cost visibility, phased traffic migration, and a final production validation.

You can adapt the sequence to your specific use case and volume profile. For the full registration and application process, see A guide to SMS short codes with AWS End User Messaging. To start configuring, navigate to the AWS End User Messaging SMS console. For the full API reference, see the AWS End User Messaging SMS documentation.


About the author

Secure multi-tenant AI agents with Amazon Bedrock AgentCore resource-based policies

Post Syndicated from Satyen Verma original https://aws.amazon.com/blogs/security/secure-multi-tenant-ai-agents-with-amazon-bedrock-agentcore-resource-based-policies/

Software as a service (SaaS) providers building AI-powered applications on Amazon Bedrock AgentCore often need to serve multiple tenants with distinct security requirements from a shared infrastructure. Some tenants require cross-account access from their own Amazon Web Services (AWS) accounts, while others mandate that traffic stay within a private virtual private cloud (VPC) for regulatory compliance. Without centralized resource-level control, managing these diverse requirements can be complex.

AgentCore supports resource-based policies, giving you centralized, resource-level control over who can access your AgentCore Runtime and AgentCore Runtime endpoint resources and under what conditions.

In this post, you walk through a multi-tenant AI customer service platform where two tenants need different levels of access to the same agent. You learn how to use resource-based policies on AgentCore to grant cross-account access for one tenant while restricting another to VPC-only traffic—all while sharing the same underlying AgentCore Runtime and AgentCore Runtime endpoint.

The multi-tenant scenario

Imagine you’re an SaaS provider who builds and operates an AI-powered customer service platform. You use AgentCore to deploy intelligent agents that handle customer inquiries, answering product questions, processing returns, and escalating complex issues to human agents.

You serve multiple enterprise clients (tenants), each with their own AWS account and unique security requirements:

  • Tenant A: Example Corp is a large retailer operating in AWS account 111122223333. Their development team is building a customer-facing chat agent that calls your AI agent to answer product questions in real time, and their admin team needs access to test agent behavior and monitor responses. Both roles must invoke the agent directly from Example Corp’s own AWS account without you having to share credentials or create AWS Identity and Access Management (IAM) users on their behalf. Example Corp has no network restriction requirements—their teams can invoke the agent from any network path as long as they have valid AWS credentials.
  • Tenant B: AnyCompany is a healthcare company operating in AWS account 444455556666. Because of regulatory (HIPAA) requirements, AI agent traffic must originate only from their private VPC (vpc-health1234). Their internal support staff uses the AI agent to assist with patient billing inquiries, which might involve protected health information (PHI). Their compliance team mandates that no API call to the agent can be made from developer laptops, public endpoints, or any network outside the controlled VPC boundary.
  • Your platform (SaaS provider) runs in account 555555555555 in the us-west-2 AWS Region. You operate an AgentCore Runtime (support-agent-runtime) that handles the core customer service logic, and an AgentCore Runtime endpoint (DEFAULT) that routes requests to the latest version of the support agent. Both tenants share this same agent infrastructure.

You can use resource-based policies to define who can access your AgentCore Runtime and AgentCore Runtime endpoint directly on the resources themselves—centralizing access control on the resource side. For cross-account scenarios like Example Corp, both a resource-based policy on your resources and an identity-based policy in the tenant’s account are required. For VPC-restricted scenarios like AnyCompany, you can use specific IAM conditions to enforce that requests originate only from an approved VPC, adding a network-level security boundary on top of identity-based controls.

Solution architecture

The following diagram shows the architecture for the multi-tenant AI customer service platform with both access patterns.

Figure 1: Architecture for the multi-tenant AI customer service platform with both access patterns

Figure 1: Architecture for the multi-tenant AI customer service platform with both access patterns

  • Your account (555555555555) with AgentCore Runtime and AgentCore Runtime endpoint
  • Example Corp’s account (111122223333) with DeveloperRole and AdminRole
  • AnyCompany’s account (444455556666) with VPC boundary and ApplicationRole
  • Policy enforcement points on both resources
  • VPC endpoint in AnyCompany’s VPC connecting to AgentCore

The SaaS provider account (555555555555) hosts the AgentCore Runtime and AgentCore Runtime endpoint that both tenants share. Example Corp (111122223333) accesses the agent cross-account using IAM roles—DeveloperRole and AdminRole—authenticated with Signature Version 4 (SigV4), the standard AWS request signing protocol. AWS evaluates both the resource-based policy on your resources and the identity-based policy in Example Corp’s account before granting access.

AnyCompany (444455556666) also accesses the agent cross-account, but with an additional constraint: all requests must originate from within their private VPC (vpc-health1234) through a VPC endpoint for AgentCore. The resource-based policy on your resources includes an explicit Deny statement that blocks any request from AnyCompany’s ApplicationRole when it doesn’t originate from the approved VPC.

In both cases, resource-based policies must be applied to both the AgentCore Runtime and AgentCore Runtime endpoint. AWS evaluates policies on both resources for InvokeAgentRuntime operations—if either resource denies access or lacks an explicit Allow, the request is denied.

Prerequisites

Before you begin, ensure you have the following:

  • An AWS account with AgentCore access and permissions to call PutResourcePolicy, GetResourcePolicy, and DeleteResourcePolicy on AgentCore resources
  • AWS Command Line Interface (AWS CLI) v2 installed and configured with the bedrock-agentcore-control API available
  • An AgentCore Runtime with SigV4 authentication and a DEFAULT AgentCore Runtime endpoint pointing to the latest runtime version

For the VPC-restricted scenario, the tenant must have a VPC endpoint for AgentCore configured in their VPC. An interface VPC endpoint creates a private connection between the tenant’s VPC and the AgentCore service without requiring traffic to traverse the public internet. For more information, see Interface VPC endpoints for Amazon Bedrock AgentCore.

Implementation

Both Example Corp and AnyCompanyoperate in separate AWS accounts from your platform. For cross-account access to AgentCore Runtime, AWS requires that both of the following allow the action:

  • A resource-based policy in your platform account applied to both the AgentCore Runtime and its AgentCore Runtime endpoint. InvokeAgentRuntime operations require an explicit Allow on both resources—if either lacks one, the request is denied.
  • An identity-based policy attached to the caller’s IAM role in the tenant’s account.

If either side is missing or denies the action, the request is denied.

Step 1: Configure cross-account access for Example Corp (Tenant A)

Example Corp’s DeveloperRole and AdminRole in account 111122223333 need to invoke your AI customer service agent. Without resource-based policies, enabling this cross-account access would typically require Example Corp’s roles to assume a role in your platform account through IAM role chaining—adding operational complexity, introducing temporary credential management, and creating additional IAM roles that must be maintained in your account for each tenant. With resource-based policies, you grant Example Corp’s roles direct access to your AgentCore Runtime and AgentCore Runtime endpoint without role chaining. Example Corp’s roles can invoke the agent directly from their own account using their own credentials, while you maintain centralized control over access on the resource side.

AgentCore Runtime resource-based policy

The following policy grants Example Corp’s DeveloperRole and AdminRole permission to invoke the agent runtime. This is the first of two resource-based policies required—it controls access to the runtime resource itself. Save this as runtime-policy.json:

{
  "Version": "2012-10-17",
  "Statement": [
    {
      "Sid": "AllowExampleCorpCrossAccountAccess",
      "Effect": "Allow",
      "Principal": {
        "AWS": [
          "arn:aws:iam::111122223333:role/DeveloperRole",
          "arn:aws:iam::111122223333:role/AdminRole"
        ]
      },
      "Action": "bedrock-agentcore:InvokeAgentRuntime",
      "Resource": "arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime"
    }
  ]
}

AgentCore Runtime endpoint resource-based policy

The following policy grants the same roles permission to invoke the AgentCore Runtime endpoint. Without this second policy, requests are allowed at the runtime level but denied at the endpoint level, and the invocation fails. Save this as endpoint-policy.json:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "AllowExampleCorpCrossAccountAccess",
            "Effect": "Allow",
            "Principal": {
                "AWS": [
                    "arn:aws:iam::111122223333:role/DeveloperRole",
                    "arn:aws:iam::111122223333:role/AdminRole"
                ]
            },
            "Action": "bedrock-agentcore:InvokeAgentRuntime",
            "Resource": "arn:aws:bedrock-agentcore:us-west-2:999999999999:runtime/support-agent-runtime/runtime-endpoint/DEFAULT"
        }
    ] 
}

To apply the resource-based policies

aws bedrock-agentcore-control put-resource-policy \--resource-arn arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime \--policy file://runtime-policy.json \--region us-west-2
aws bedrock-agentcore-control put-resource-policy \--resource-arn arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime/runtime-endpoint/DEFAULT \--policy file://endpoint-policy.json \--region us-west-2

To verify the resource-based policies

aws bedrock-agentcore-control get-resource-policy \--resource-arn arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime \--region us-west-2
aws bedrock-agentcore-control get-resource-policy \--resource-arn arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime/runtime-endpoint/DEFAULT \--region us-west-2

Configure an identity-based policy (Example Corp’s account)

Resource-based policies alone aren’t sufficient for cross-account access. Example Corp must also attach an identity-based policy to DeveloperRole and AdminRole in their account (111122223333) that allows the same action on your resources. Without this policy on the tenant side, IAM denies the cross-account request even though your resource-based policies allow it.

Example Corp attaches the following policy to both DeveloperRole and AdminRole:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "AllowInvokeAgentRuntime",
            "Effect": "Allow",
            "Action": "bedrock-agentcore:InvokeAgentRuntime",
            "Resource": [
                "arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime",
                "arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime/runtime-endpoint/DEFAULT"
            ]
        }
    ] 
}

Attach this policy to both DeveloperRole and AdminRole in Example Corp’s account.

Step 2: Configure cross-account with VPC-restricted access for AnyCompany (Tenant B)

AnyCompany operates under HIPAA compliance requirements and mandates that all traffic to your agent stays within a private network path. Like Example Corp, AnyCompany needs cross-account access from account 444455556666—but with an additional constraint, requests must originate from their VPC vpc-health1234 through an interface VPC endpoint. Any request from outside this VPC is denied, even if it comes from AnyCompany’s ApplicationRole.

Resource-based policies (your platform account): To enforce this, you update the resource-based policies on both the AgentCore Runtime and AgentCore Runtime endpoint. Each policy includes an Allow statement that grants ApplicationRole permission to invoke the agent, paired with a Deny statement that blocks any request not originating from vpc-health1234. In the following policy, the Deny statement uses StringNotEquals on aws:SourceVpc . When a request arrives through an interface VPC endpoint, AWS populates this key with the VPC ID. If it doesn’t match vpc-health1234, or if the key is absent because no VPC endpoint was used, the Deny takes effect. Because an explicit Deny overrides any Allow from any policy, this pattern helps ensure that no other identity-based or resource-based policy can inadvertently grant AnyCompany access from outside the VPC. Add the following statements to runtime-policy-v2.json alongside the Example Corp statement from Step 1:

{
  "Sid": "AllowAnyCompanyCrossAccountAccess",
  "Effect": "Allow",
  "Principal": {
    "AWS": "arn:aws:iam::444455556666:role/ApplicationRole"
  },
  "Action": "bedrock-agentcore:InvokeAgentRuntime",
  "Resource": "arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime"
},
{
  "Sid": "DenyAnyCompanyOutsideVpc",
  "Effect": "Deny",
  "Principal": {
    "AWS": "arn:aws:iam::444455556666:role/ApplicationRole"
  },
  "Action": "bedrock-agentcore:InvokeAgentRuntime",
  "Resource": "arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime",
  "Condition": {
    "StringNotEquals": {
      "aws:SourceVpc": "vpc-health1234"
    }
  }
}

AgentCore Runtime endpoint resource-based policy

Add the equivalent statement to endpoint-policy-v2.json:

{
    "Sid": "AllowAnyCompanyCrossAccountAccess",
    "Effect": "Allow",
    "Principal": {
        "AWS": "arn:aws:iam::444455556666:role/ApplicationRole"
    },
    "Action": "bedrock-agentcore:InvokeAgentRuntime",
    "Resource": "arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime/runtime-endpoint/DEFAULT"
},
{
    "Sid": "DenyHealthFirstOutsideVpc",
    "Effect": "Deny",
    "Principal": {
        "AWS": "arn:aws:iam::444455556666:role/ApplicationRole"
    },
    "Action": "bedrock-agentcore:InvokeAgentRuntime",
    "Resource": "arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime/runtime-endpoint/DEFAULT",
    "Condition": {
        "StringNotEquals": {
            "aws:SourceVpc": "vpc-health1234"
        }
    }
}

Because put-resource-policy replaces the entire policy on a resource, your updated policy files must include both the preceding AnyCompany statments and the Example Corp statements from Step 1.

Apply the updated resource-based policies

aws bedrock-agentcore-control put-resource-policy \
	--resource-arn arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime \
	--policy file://runtime-policy-v2.json \
	--region us-west-2 

aws bedrock-agentcore-control put-resource-policy \
	--resource-arn arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime/runtime-endpoint/DEFAULT \
	--policy file://endpoint-policy-v2.json \
	--region us-west-2

Verify the updated policies

After applying the final policies, verify them using the get-resource-policy command:

# Verify Agent Runtime policy 
aws bedrock-agentcore-control get-resource-policy \
	--resource-arn arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime \
	--region us-west-2 

# Verify Agent Runtime Endpoint policy 
aws bedrock-agentcore-control get-resource-policy \
	--resource-arn arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime/runtime-endpoint/DEFAULT \
	--region us-west-2

Identity-based policy (AnyCompany’s account)

AnyCompany must attach an identity-based policy to ApplicationRole in their account 444455556666 that allows the same InvokeAgentRuntime on your resources in account 555555555555. Without this policy on the tenant side, IAM denies the cross-account request even though your resource-based policies allow it.

AnyCompany attaches the following policy to ApplicationRole:

{
    "Version": "2012-10-17",
    "Statement": [
        {
            "Sid": "AllowInvokeAgentRuntime",
            "Effect": "Allow",
            "Action": "bedrock-agentcore:InvokeAgentRuntime",
            "Resource": [
                "arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime",
                "arn:aws:bedrock-agentcore:us-west-2:555555555555:runtime/support-agent-runtime/runtime-endpoint/DEFAULT"
            ]
        }
    ] 
}

The VPC restriction is enforced entirely on resource account through the resource-based policy condition, AnyCompany’s identity-based policy doesn’t need VPC conditions. This keeps the tenant-side configuration straightforward while you maintain centralized network-level control.

OAuth authentication considerations

The policies in this post use SigV4 authentication with specific IAM role principals. If your AgentCore Runtime or AgentCore Gateway is configured with OAuth authentication instead, the principal structure changes. OAuth-authenticated resources require a wildcard principal (“Principal": "*") because the caller identity comes from a JSON Web Token (JWT) validated before policy evaluation. Anonymous or unauthenticated requests are rejected before the policy is evaluated, so the wildcard principal doesn’t grant open access. To restrict OAuth-authenticated requests to a specific VPC, combine the wildcard principal with a VPC condition in the resource-based policy. IAM principal-based condition keys such as aws:PrincipalAccount and aws:PrincipalOrgID aren’t populated in the OAuth authentication context—only supported network-level condition keys (such as aws:SourceVpc, aws:SourceVpce, aws:SourceIp) are available for use in resource-based policies with OAuth. For more details, see Resource-based policies for Amazon Bedrock AgentCore.

Understanding policy evaluation

To understand how AWS evaluates these policies when a request arrives, consider the following scenarios:

Caller or principal Network Identity-based policy (tenant side) Runtime resource-based policy Runtime endpoint resource-based policy Final policy evaluation result
Example Corp Any network Allows Allows Allows Allowed
AnyCompany From Allows Allows ( does not match) Allows ( does not match) Allowed
AnyCompany Outside VPC Allows matches matches Denied
Any other cross-account role Any network Allows No matching No matching Denied
Any other cross-account role Any network No policy Allows Allows Denied

Conclusion and next steps

In this post, you learned how to use resource-based policies on AgentCore to secure a multi-tenant AI platform with distinct access patterns for each tenant:

  • Example Corp gets seamless cross-account integration, their development and admin teams can invoke your AI agent directly from their own AWS account without credential management.
  • AnyCompany gets the strict network-level isolation their compliance team requires, the AI agent is accessible only from within their private VPC, ensuring that interactions involving potential PHI — stay within the controlled network boundary

Both tenants share the same underlying AgentCore Runtime and AgentCore Runtime endpoint, yet each has tailored security controls enforced at the resource level. his approach avoids per-tenant infrastructure duplication while satisfying each tenant’s security posture, a challenge you likely face when onboarding tenants with different compliance postures. Resource-based policies complement identity-based IAM policies, giving you layered control over which principals can invoke which agents, and from which network paths.

Next steps

If you have feedback about this post, submit comments in the Comments section below.


Satyen Verma

Satyen Verma

Satyen is a Software Engineer at AWS building secure and scalable runtime systems for Amazon Bedrock AgentCore. He focuses on enabling reliable, high-performance agentic AI applications for customers worldwide.

Zohreh Norouzi

Zohreh Norouzi

Zohreh is a Security Solutions Architect at AWS. She helps customers make good security choices and accelerate their journey to the AWS Cloud. She has been actively involved in generative AI security initiatives across APJ, using her expertise to help customers build secure generative AI solutions at scale.

Vijay Kumar Samanthapudi

Vijay Kumar Samanthapudi

Vijay is a Software Engineer at AWS building secure and scalable runtime systems for Amazon Bedrock AgentCore. He focuses on enabling reliable, high-performance agentic AI applications for customers worldwide.

Satveer Khurpa

Satveer Khurpa

Satveer is a Sr. WW Specialist Solutions Architect, Amazon Bedrock AgentCore at AWS, specializing in agentic AI security with a focus on AgentCore Identity and Security. He uses his expertise in cloud-based architectures to help clients design and deploy secure agentic AI systems across diverse industries.

Prajit Pabbati

Prajit Pabbati

Prajit is a Software Development Manager at AWS building secure and scalable runtime systems for Amazon Bedrock AgentCore.