Tag Archives: microsoft azure

Cable cuts, storms, and DNS: a look at Internet disruptions in Q4 2025

Post Syndicated from David Belson original https://blog.cloudflare.com/q4-2025-internet-disruption-summary/

In 2025, we observed over 180 Internet disruptions spurred by a variety of causes – some were brief and partial, while others were complete outages lasting for days. In the fourth quarter, we tracked only a single government-directed Internet shutdown, but multiple cable cuts wreaked havoc on connectivity in several countries. Power outages and extreme weather disrupted Internet services in multiple places, and the ongoing conflict in Ukraine impacted connectivity there as well. As always, a number of the disruptions we observed were due to technical problems – with some acknowledged by the relevant providers, while others had unknown causes. In addition, incidents at several hyperscaler cloud platforms and Cloudflare impacted the availability of websites and applications. 

This post is intended as a summary overview of observed and confirmed disruptions and is not an exhaustive or complete list of issues that have occurred during the quarter. These anomalies are detected through significant deviations from expected traffic patterns observed across our network. Check out the Cloudflare Radar Outage Center for a full list of verified anomalies and confirmed outages. 

Government-directed

Tanzania

The Internet was shut down in Tanzania on October 29 as violent protests took place during the country’s presidential election. Traffic initially fell around 12:30 local time (09:30 UTC), dropping more than 90% lower than the previous week. The disruption lasted approximately 26 hours, with traffic beginning to return around 14:30 local time (11:30 UTC) on October 30. However, that restoration proved to be quite brief, with a significant decrease in traffic occurring around 16:15 local time (13:15 UTC), approximately two hours after it returned. This second near-complete outage lasted until November 3, when traffic aggressively returned after 17:00 local time (14:00 UTC). Nominal drops in announced IPv4 and IPv6 address space were also observed during the shutdown, but there was never a complete loss of announcements, which would have signified a total disconnection of the country from the Internet. (Autonomous systems announce IP address space to other Internet providers, letting them know what blocks of IP addresses they are responsible for.)

Tanzania’s president later expressed sympathy for the members of the diplomatic community and foreigners residing in the country regarding the impact of the Internet shutdown. Internet and social media services were also restricted in 2020 ahead of the country’s general elections.

Cable cuts

Digicel Haiti

Digicel Haiti is unfortunately no stranger to Internet disruptions caused by cable cuts, and the network experienced two more such incidents during the fourth quarter. On October 16, traffic from Digicel Haiti (AS27653) began to fall at 14:30 local time (18:30 UTC), reaching near zero at 16:00 local time (20:00 UTC). A translated X post from the company’s Director General noted: “We advise our clientele that @DigicelHT is experiencing 2 cuts on its international fiber optic infrastructure.” Traffic began to recover after 17:00 local time (21:00 UTC), and reached expected levels within the following hour. At 17:33 local time (21:34 UTC), the Director General posted that “the first fiber on the international infrastructure has been repaired” and service had been restored. 

On November 25, another translated X post from the provider’s Director General stated that its “international optical fiber infrastructure on National Road 1” had been cut. We observed traffic dropping on Digicel’s network approximately an hour earlier, with a complete outage observed between 02:00 – 08:00 local time (07:00 – 13:00 UTC). A follow-on X post at 08:22 local time (13:22 UTC) stated that all services had been restored.

Cybernet/StormFiber (Pakistan)

At 17:30 local time (12:30 UTC) on October 20, Internet traffic for Cybernet/StormFiber (AS9541) dropped sharply, falling to a level approximately 50% the same time a week prior. At the same time, the network’s announced IPv4 address space dropped by over a third. The cause of these shifts was damage to the PEACE submarine cable, which suffered a cut in the Red Sea near Sudan. 

PEACE is one of several submarine cable systems (including IMEWE and SEA-ME-WE-4) that carry international Internet traffic for Pakistani providers. The provider pledged to fully restore service by October 27, but traffic and announced IPv4 address space had recovered to near expected levels by around 02:00 local time on October 21 (21:00 UTC on October 20).

Camtel, MTN Cameroon, Orange Cameroun

Unusual traffic patterns observed across multiple Internet providers in Cameroon on October 23 were reportedly caused by problems on the WACS (West Africa Cable System) submarine cable, which connects countries along the west coast of Africa to Portugal. 

A (translated) published report stated that MTN informed subscribers that “following an incident on the WACS fiber optic cable, Internet service is temporarily disrupted” and Orange Cameroun informed subscribers that “due to an incident on the international access fiber, Internet service is disrupted.” An X post from Camtel stated “Cameroon Telecommunications (CAMTEL) wishes to inform the public that a technical incident involving WACS cable equipment in Batoke (LIMBE) occurred in the early hours of 23 October 2025, causing Internet connectivity disruptions throughout the country.” 

Traffic across the impacted providers originally fell just at around  05:00 local time (04:00 UTC) before recovering to expected levels around 22:00 local time (21:00 UTC). Traffic across these networks was quite volatile during the day, dropping 90-99% at times. It isn’t clear what caused the visible spikiness in the traffic pattern—possibly attempts to shift Internet traffic to other submarine cable systems that connect to Cameroon. Announced IP address space from MTN Cameroon and Orange Cameroon dropped during this period as well, although Camtel’s announced IP address space did not change.

Connectivity in the Central African Republic and Republic of Congo was also reportedly impacted by the WACS issues.

Claro Dominicana

On December 9, we saw traffic from Claro Dominicana (AS6400), an Internet provider in the Dominican Republic, drop sharply around 12:15 local time (16:15 UTC). Traffic levels fell again around 14:15 local time (18:15 UTC), bottoming out 77% lower than the previous week before quickly returning to expected levels. The connectivity disruption was likely caused by two fiber optic outages, as an X post from the provider during the outage noted that they were “causing intermittency and slowness in some services.” A subsequent post on X from Claro stated that technicians had restored Internet services nationwide by repairing the severed fiber optic cables.

Power outages

Dominican Republic

According to a (translated) X post from the Empresa de Transmisión Eléctrica Dominicana (ETED), a transmission line outage caused an interruption in electrical service in the Dominican Republic on November 11. This power outage impacted Internet traffic from the country, resulting in a nearly 50% drop in traffic compared to the prior week, starting at 13:15 local time (17:15 UTC). Traffic levels remained lower until approximately 02:00 local time (06:00 UTC) on December 12, with a later (translated) X post from ETED noting “At 2:20 a.m. we have completed the recovery of the national electrical system, supplying 96% of the demand…

A subsequent technical report found that “the blackout began at the 138 kV San Pedro de Macorís I substation, where a live line was manually disconnected, triggering a high-intensity short circuit. Protection systems responded immediately, but the fault caused several nearby lines to disconnect, separating 575 MW of generation in the eastern region from the rest of the grid. The imbalance caused major power plants to trip automatically as part of their built-in safety mechanisms.

Kenya

On December 9, a major power outage impacted multiple regions across Kenya. Kenya Power explained that the outage “was triggered by an incident on the regional Kenya-Uganda interconnected power network, which caused a disturbance on the Kenyan side of the system” and claimed that “[p]ower was restored to most of the affected areas within approximately 30 minutes.” However, impacts to Internet connectivity lasted for nearly four hours, between 19:15 – 23:00 local time (16:15 – 20:00 UTC). The power outage caused traffic to drop as much as 18% at a national level, with the traffic shifts most visible in Nakuru County and Kaimbu County.

Military action

Odesa, Ukraine

Russian drone strikes on the Odesa region in Ukraine on December 12 damaged warehouses and energy infrastructure, with the latter causing power outages in parts of the region. Those outages disrupted Internet connectivity, resulting in traffic dropping by as much as 57% as compared to the prior week. After the initial drop at midnight on December 13 (22:00 UTC on December 12), traffic gradually recovered over the following several days, returning to expected levels around 14:30 local time (12:30 UTC) on December 16.

Weather

Jamaica

Hurricane Melissa made landfall on Jamaica on October 28 and left a trail of damage and destruction in its path. Associated power outages and infrastructure damage impacted Internet connectivity, causing traffic to initially drop by approximately half, starting around 06:15 local time (11:15 UTC), ultimately reaching as much as 70% lower than the previous week. Internet traffic from Jamaica remained well below pre-hurricane levels for several days, and ultimately started to make greater progress towards expected levels during the morning of November 4. It can often take weeks or months for Internet traffic from a country to return to “normal” levels following storms that cause massive and widespread damage – while power may be largely restored within several days, damage to physical infrastructure takes significantly longer to address.

Sri Lanka & Indonesia

On November 26, Cyclone Senyar caused catastrophic floods and landslides in Sri Lanka and Indonesia, killing over 1,000 people and damaging telecommunications and power infrastructure across these countries. The infrastructure damage resulted in disruptions to Internet connectivity, and resultant lower traffic levels, across multiple regions.

In Sri Lanka, regions outside the main Western Province were the most affected, and several provinces saw traffic drop between 80% and 95% as compared to the prior week, including North Western, Southern, Uva, Eastern, Northern, North Central, and Sabaragamuwa.

In Indonesia, Aceh and the Sumatra regions saw the biggest Internet disruptions. In Aceh, traffic initially dropped over 75% as compared to the previous week. In Sumatra, North Sumatra was the most affected, with an early 30% drop as compared to the previous week, before starting to recover more actively the following week.

Known or unspecified technical problems

Smartfren (Indonesia)

On October 3, subscribers to Indonesian Internet provider Smartfren (AS18004) experienced a service disruption. The issues were acknowledged by the provider in an X post, which stated (in translation), “Currently, telephone, SMS and data services are experiencing problems in several areas.” Traffic from the provider fell as much as 84%, starting around 09:00 local time (02:00 UTC). The disruption lasted for approximately eight hours, as traffic returned to expected levels around 17:00 local time (10:00 UTC). Smartfren did not provide any additional information on what caused the service problems.

Vodafone UK

Major British Internet provider Vodafone UK (AS5378 & AS25135) experienced a brief service outage on October 23. At 15:00 local time (14:00 UTC), traffic on both Vodafone ASNs dropped to zero. Announced IPv4 address space from AS5378 fell by 75%, while announced IPv4 address space from AS25135 disappeared entirely. Both Internet traffic and address space recovered two hours later, returning to expected levels around 17:00 local time (16:00 UTC). Vodafone did not provide any information on their social media channels about the cause of the outage, and their network status checker page was also unavailable during the outage.

Fastweb (Italy)

According to a published report, a DNS resolution issue disrupted Internet services for customers of Italian provider Fastweb (AS12874) on October 22, causing observed traffic volumes to drop by over 75%. Fastweb acknowledged the issue, which impacted wired Internet customers between 09:30 – 13:00 local time (08:30 – 12:00 UTC).

Although not an Internet outage caused by connectivity failure, the impact of DNS resolution issues on Internet traffic is very similar. When a provider’s DNS resolver is experiencing problems, switching to a service like Cloudflare’s 1.1.1.1 public DNS resolver will often restore connectivity.

SBIN, MTN Benin, Etisalat Benin

On December 7, a concurrent drop in traffic was observed across SBIN (AS28683), MTN Benin (AS37424), and Etisalat Benin (AS37136). Between 18:30 – 19:30 local time (17:30 – 18:30 UTC), traffic dropped as much as 80% as compared to the prior week at a country level, nearly 100% at Etisalat and MTN, and over 80% at SBIN.

While an attempted coup had taken place earlier in the day, it is unclear whether the observed Internet disruption was related in any way. From a routing perspective, all three impacted networks share Cogent (AS174) as an upstream provider, so a localized issue at Cogent may have contributed to the brief outage.  

Cellcom Israel

According to a reported announcement from Israeli provider Cellcom (AS1680), on December 18, there was “a malfunction affecting Internet connectivity that is impacting some of our customers.” This malfunction dropped traffic nearly 70% as compared to the prior week, and occurred between 09:30 – 11:00 local time (07:30 – 09:00 UTC). The “malfunction” may have been a DNS failure, according to a published report.

Partner Communications (Israel)

Closing out 2025, on December 30, a major technical failure at Israeli provider Partner Communications (AS12400) disrupted mobile, TV, and Internet services across the country. Internet traffic from Partner fell by two-thirds as compared to the previous week between 14:00 – 15:00 local time (12:00 – 13:00 UTC). During the outage, queries to Cloudflare’s 1.1.1.1 public DNS resolver spiked, suggesting that the problem may have been related to Partner’s DNS infrastructure. However, the provider did not publicly confirm what caused the outage.

Cloud Platforms

During the fourth quarter, we launched a new Cloud Observatory page on Radar that tracks availability and performance issues at a region level across hyperscaler cloud platforms, including Amazon Web Services, Microsoft Azure, Google Cloud Platform, and Oracle Cloud Infrastructure.

Amazon Web Services

On October 20, the Amazon Web Services us-east-1 region in Northern Virginia experienced “increased error rates and latencies” that affected multiple services within the region. The issues impacted not only customers with public-facing Web sites and applications that rely on infrastructure within the region, but also Cloudflare customers that have origin resources hosted in us-east-1.

We began to see the impact of the problems around 06:30 UTC, as the share of error (5xx-class) responses began to climb, reaching as high as 17% around 08:00 UTC. The number of failures encountered when attempting to connect to origins in us-east-1 climbed as well, peaking around 12:00 UTC.

The impact could also be clearly seen in key network performance metrics, which remained elevated throughout the incident, returning to normal levels just before the end of the incident, around 23:00 UTC. Both TCP and TLS handshake durations got progressively worse throughout the incident—these metrics measure the amount of time needed for Cloudflare to establish TCP and TLS connections respectively with customer origin servers in us-east-1. In addition, the amount of time elapsed before Cloudflare received response headers from the origin increased significantly during the first several hours of the incident, before gradually returning to expected levels.

Microsoft Azure

On October 29, Microsoft Azure experienced an incident impacting Azure Front Door, its content delivery network service. According to Azure’s report on the incident, “A specific sequence of customer configuration changes, performed across two different control plane build versions, resulted in incompatible customer configuration metadata being generated. These customer configuration changes themselves were valid and non-malicious – however they produced metadata that, when deployed to edge site servers, exposed a latent bug in the data plane. This incompatibility triggered a crash during asynchronous processing within the data plane service.

The incident report marked the start time at 15:41 UTC, although we observed the volume of failed connection attempts to Azure-hosted origins begin to climb about 45 minutes prior. The TCP and TLS handshake metrics also became more volatile during the incident period, with TCP handshakes taking over 50% longer at times, and TLS handshakes taking nearly 200% longer at peak. The impacted metrics began to improve after 20:00 UTC, and according to Microsoft, the incident ended at 00:05 UTC on October 30.

Cloudflare

In addition to the outages discussed above, Cloudflare also experienced two disruptions during the fourth quarter. While these were not Internet outages in the classic sense, they did prevent users from accessing Web sites and applications delivered and protected by Cloudflare when they occurred.

The first incident took place on November 18, and was caused by a software failure triggered by a change to one of our database systems’ permissions, which caused the database to output multiple entries into a “feature file” used by our Bot Management system. Additional details, including a root cause analysis and timeline, can be found in the associated blog post.

The second incident occurred on December 5, and impacted a subset of customers, accounting for approximately 28% of all HTTP traffic served by Cloudflare. It was triggered by changes being made to our request body parsing logic while attempting to detect and mitigate a newly disclosed industry-wide React Server Components vulnerability. A post-mortem blog post contains additional details, including a root cause analysis and timeline.

For more information about the work underway at Cloudflare to prevent outages like these from happening again, check out our blog post detailing “Code Orange: Fail Small.”

Conclusion

The disruptions observed in the fourth quarter underscore the importance of real-time data in maintaining global connectivity. Whether it’s a government-ordered shutdown or a minor technical issue, transparency allows the technical community to respond faster and more effectively. We will continue to track these shifts on Cloudflare Radar, providing the insights needed to navigate the complexities of modern networking. We share our observations on the Cloudflare Radar Outage Center, via social media, and in posts on blog.cloudflare.com. Follow us on social media at @CloudflareRadar (X), noc.social/@cloudflareradar (Mastodon), and radar.cloudflare.com (Bluesky), or contact us via email.

As a reminder, while these blog posts feature graphs from Radar and the Radar Data Explorer, the underlying data is available from our API. You can use the API to retrieve data to do your own local monitoring or analysis, or you can use the Radar MCP server to incorporate Radar data into your AI tools.
Magic Cloud Networking simplifies security, connectivity, and management of public clouds

Post Syndicated from Steve Welham original https://blog.cloudflare.com/introducing-magic-cloud-networking


Today we are excited to announce Magic Cloud Networking, supercharged by Cloudflare’s recent acquisition of Nefeli Networks’ innovative technology. These new capabilities to visualize and automate cloud networks will give our customers secure, easy, and seamless connection to public cloud environments.

Public clouds offer organizations a scalable and on-demand IT infrastructure without the overhead and expense of running their own datacenter. Cloud networking is foundational to applications that have been migrated to the cloud, but is difficult to manage without automation software, especially when operating at scale across multiple cloud accounts. Magic Cloud Networking uses familiar concepts to provide a single interface that controls and unifies multiple cloud providers’ native network capabilities to create reliable, cost-effective, and secure cloud networks.

Nefeli’s approach to multi-cloud networking solves the problem of building and operating end-to-end networks within and across public clouds, allowing organizations to securely leverage applications spanning any combination of internal and external resources. Adding Nefeli’s technology will make it easier than ever for our customers to connect and protect their users, private networks and applications.

Why is cloud networking difficult?

Compared with a traditional on-premises data center network, cloud networking promises simplicity:

  • Much of the complexity of physical networking is abstracted away from users because the physical and ethernet layers are not part of the network service exposed by the cloud provider.
  • There are fewer control plane protocols; instead, the cloud providers deliver a simplified software-defined network (SDN) that is fully programmable via API.
  • There is capacity — from zero up to very large — available instantly and on-demand, only charging for what you use.

However, that promise has not yet been fully realized. Our customers have described several reasons cloud networking is difficult:

  • Poor end-to-end visibility: Cloud network visibility tools are difficult to use and silos exist even within single cloud providers that impede end-to-end monitoring and troubleshooting.
  • Faster pace: Traditional IT management approaches clash with the promise of the cloud: instant deployment available on-demand. Familiar ClickOps and CLI-driven procedures must be replaced by automation to meet the needs of the business.
  • Different technology: Established network architectures in on-premises environments do not seamlessly transition to a public cloud. The missing ethernet layer and advanced control plane protocols were critical in many network designs.
  • New cost models: The dynamic pay-as-you-go usage-based cost models of the public clouds are not compatible with established approaches built around fixed cost circuits and 5-year depreciation. Network solutions are often architected with financial constraints, and accordingly, different architectural approaches are sensible in the cloud.
  • New security risks: Securing public clouds with true zero trust and least-privilege demands mature operating processes and automation, and familiarity with cloud-specific policies and IAM controls.
  • Multi-vendor: Oftentimes enterprise networks have used single-vendor sourcing to facilitate interoperability, operational efficiency, and targeted hiring and training. Operating a network that extends beyond a single cloud, into other clouds or on-premises environments, is a multi-vendor scenario.

Nefeli considered all these problems and the tensions between different customer perspectives to identify where the problem should be solved.

Trains, planes, and automation

Consider a train system. To operate effectively it has three key layers:

  • tracks and trains
  • electronic signals
  • a company to manage the system and sell tickets.

A train system with good tracks, trains, and signals could still be operating below its full potential because its agents are unable to keep up with passenger demand. The result is that passengers cannot plan itineraries or purchase tickets.

The train company eliminates bottlenecks in process flow by simplifying the schedules, simplifying the pricing, providing agents with better booking systems, and installing automated ticket machines. Now the same fast and reliable infrastructure of tracks, trains, and signals can be used to its full potential.

Solve the right problem

In networking, there are an analogous set of three layers, called the networking planes:

  • Data Plane: the network paths that transport data (in the form of packets) from source to destination.
  • Control Plane: protocols and logic that change how packets are steered across the data plane.
  • Management Plane: the configuration and monitoring interfaces for the data plane and control plane.

In public cloud networks, these layers map to:

  • Cloud Data Plane: The underlying cables and devices are exposed to users as the Virtual Private Cloud (VPC) or Virtual Network (VNet) service that includes subnets, routing tables, security groups/ACLs and additional services such as load-balancers and VPN gateways.
  • Cloud Control Plane: In place of distributed protocols, the cloud control plane is a software defined network (SDN) that, for example, programs static route tables. (There is limited use of traditional control plane protocols, such as BGP to interface with external networks and ARP to interface with VMs.)
  • Cloud Management Plane: An administrative interface with a UI and API which allows the admin to fully configure the data and control planes. It also provides a variety of monitoring and logging capabilities that can be enabled and integrated with 3rd party systems.

Like our train example, most of the problems that our customers experience with cloud networking are in the third layer: the management plane.

Nefeli simplifies, unifies, and automates cloud network management and operations.

Avoid cost and complexity

One common approach to tackle management problems in cloud networks is introducing Virtual Network Functions (VNFs), which are virtual machines (VMs) that do packet forwarding, in place of native cloud data plane constructs. Some VNFs are routers, firewalls, or load-balancers ported from a traditional network vendor’s hardware appliances, while others are software-based proxies often built on open-source projects like NGINX or Envoy. Because VNFs mimic their physical counterparts, IT teams could continue using familiar management tooling, but VNFs have downsides:

  • VMs do not have custom network silicon and so instead rely on raw compute power. The VM is sized for the peak anticipated load and then typically runs 24x7x365. This drives a high cost of compute regardless of the actual utilization.
  • High-availability (HA) relies on fragile, costly, and complex network configuration.
  • Service insertion — the configuration to put a VNF into the packet flow — often forces packet paths that incur additional bandwidth charges.
  • VNFs are typically licensed similarly to their on-premises counterparts and are expensive.
  • VNFs lock in the enterprise and potentially exclude them benefitting from improvements in the cloud’s native data plane offerings.

For these reasons, enterprises are turning away from VNF-based solutions and increasingly looking to rely on the native network capabilities of their cloud service providers. The built-in public cloud networking is elastic, performant, robust, and priced on usage, with high-availability options integrated and backed by the cloud provider’s service level agreement.

In our train example, the tracks and trains are good. Likewise, the cloud network data plane is highly capable. Changing the data plane to solve management plane problems is the wrong approach. To make this work at scale, organizations need a solution that works together with the native network capabilities of cloud service providers.

Nefeli leverages native cloud data plane constructs rather than third party VNFs.

Introducing Magic Cloud Networking

The Nefeli team has joined Cloudflare to integrate cloud network management functionality with Cloudflare One. This capability is called Magic Cloud Networking and with it, enterprises can use the Cloudflare dashboard and API to manage their public cloud networks and connect with Cloudflare One.

End-to-end

Just as train providers are focused only on completing train journeys in their own network, cloud service providers deliver network connectivity and tools within a single cloud account. Many large enterprises have hundreds of cloud accounts across multiple cloud providers. In an end-to-end network this creates disconnected networking silos which introduce operational inefficiencies and risk.

Imagine you are trying to organize a train journey across Europe, and no single train company serves both your origin and destination. You know they all offer the same basic service: a seat on a train. However, your trip is difficult to arrange because it involves multiple trains operated by different companies with their own schedules and ticketing rates, all in different languages!

Magic Cloud Networking is like an online travel agent that aggregates multiple transportation options, books multiple tickets, facilitates changes after booking, and then delivers travel status updates.

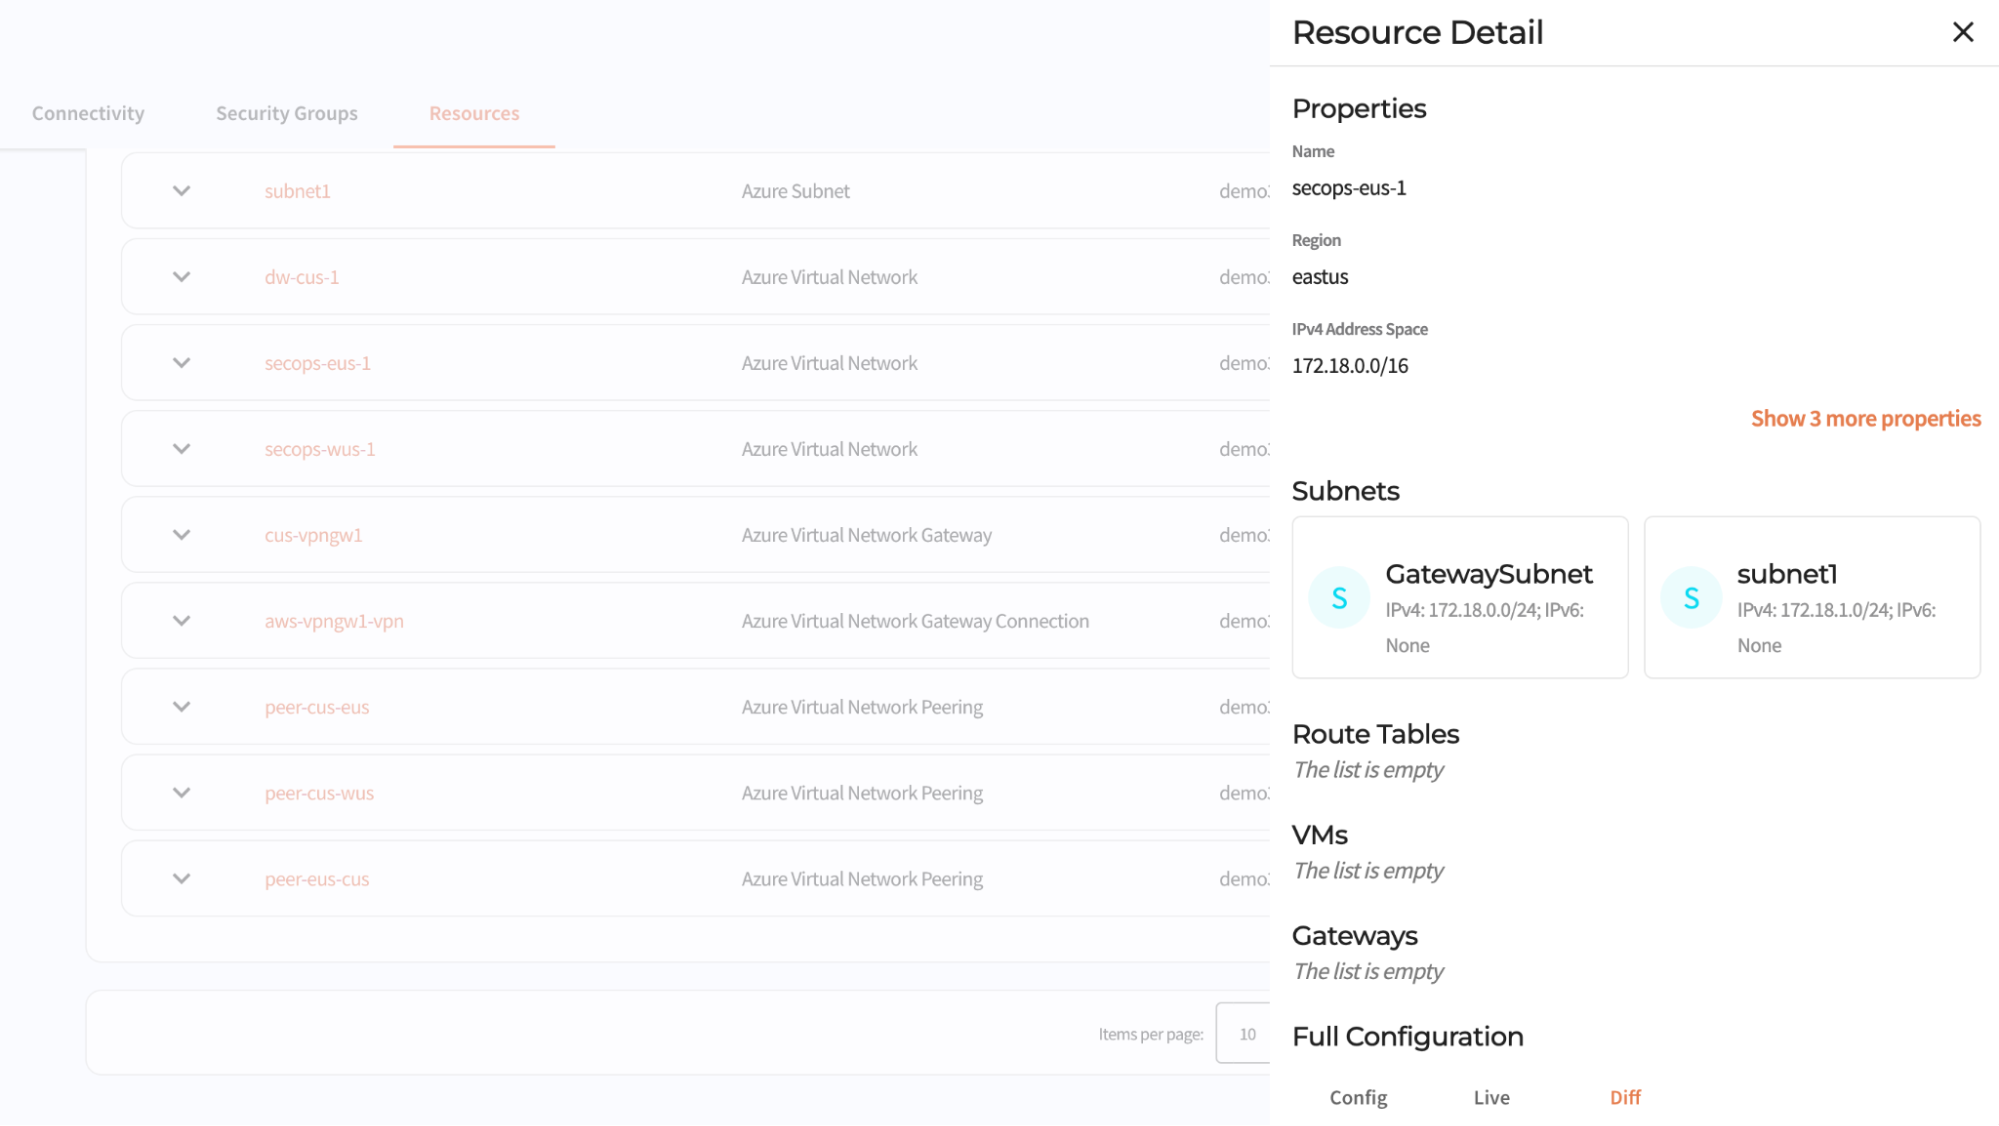
Through the Cloudflare dashboard, you can discover all of your network resources across accounts and cloud providers and visualize your end-to-end network in a single interface. Once Magic Cloud Networking discovers your networks, you can build a scalable network through a fully automated and simple workflow.

Resource inventory shows all configuration in a single and responsive UI

Taming per-cloud complexity

Public clouds are used to deliver applications and services. Each cloud provider offers a composable stack of modular building blocks (resources) that start with the foundation of a billing account and then add on security controls. The next foundational layer, for server-based applications, is VPC networking. Additional resources are built on the VPC network foundation until you have compute, storage, and network infrastructure to host the enterprise application and data. Even relatively simple architectures can be composed of hundreds of resources.

The trouble is, these resources expose abstractions that are different from the building blocks you would use to build a service on prem, the abstractions differ between cloud providers, and they form a web of dependencies with complex rules about how configuration changes are made (rules which differ between resource types and cloud providers). For example, say I create 100 VMs, and connect them to an IP network. Can I make changes to the IP network while the VMs are using the network? The answer: it depends.

Magic Cloud Networking handles these differences and complexities for you. It configures native cloud constructs such as VPN gateways, routes, and security groups to securely connect your cloud VPC network to Cloudflare One without having to learn each cloud’s incantations for creating VPN connections and hubs.

Continuous, coordinated automation

Returning to our train system example, what if the railway maintenance staff find a dangerous fault on the railroad track? They manually set the signal to a stop light to prevent any oncoming trains using the faulty section of track. Then, what if, by unfortunate coincidence, the scheduling office is changing the signal schedule, and they set the signals remotely which clears the safety measure made by the maintenance crew? Now there is a problem that no one knows about and the root cause is that multiple authorities can change the signals via different interfaces without coordination.

The same problem exists in cloud networks: configuration changes are made by different teams using different automation and configuration interfaces across a spectrum of roles such as billing, support, security, networking, firewalls, database, and application development.

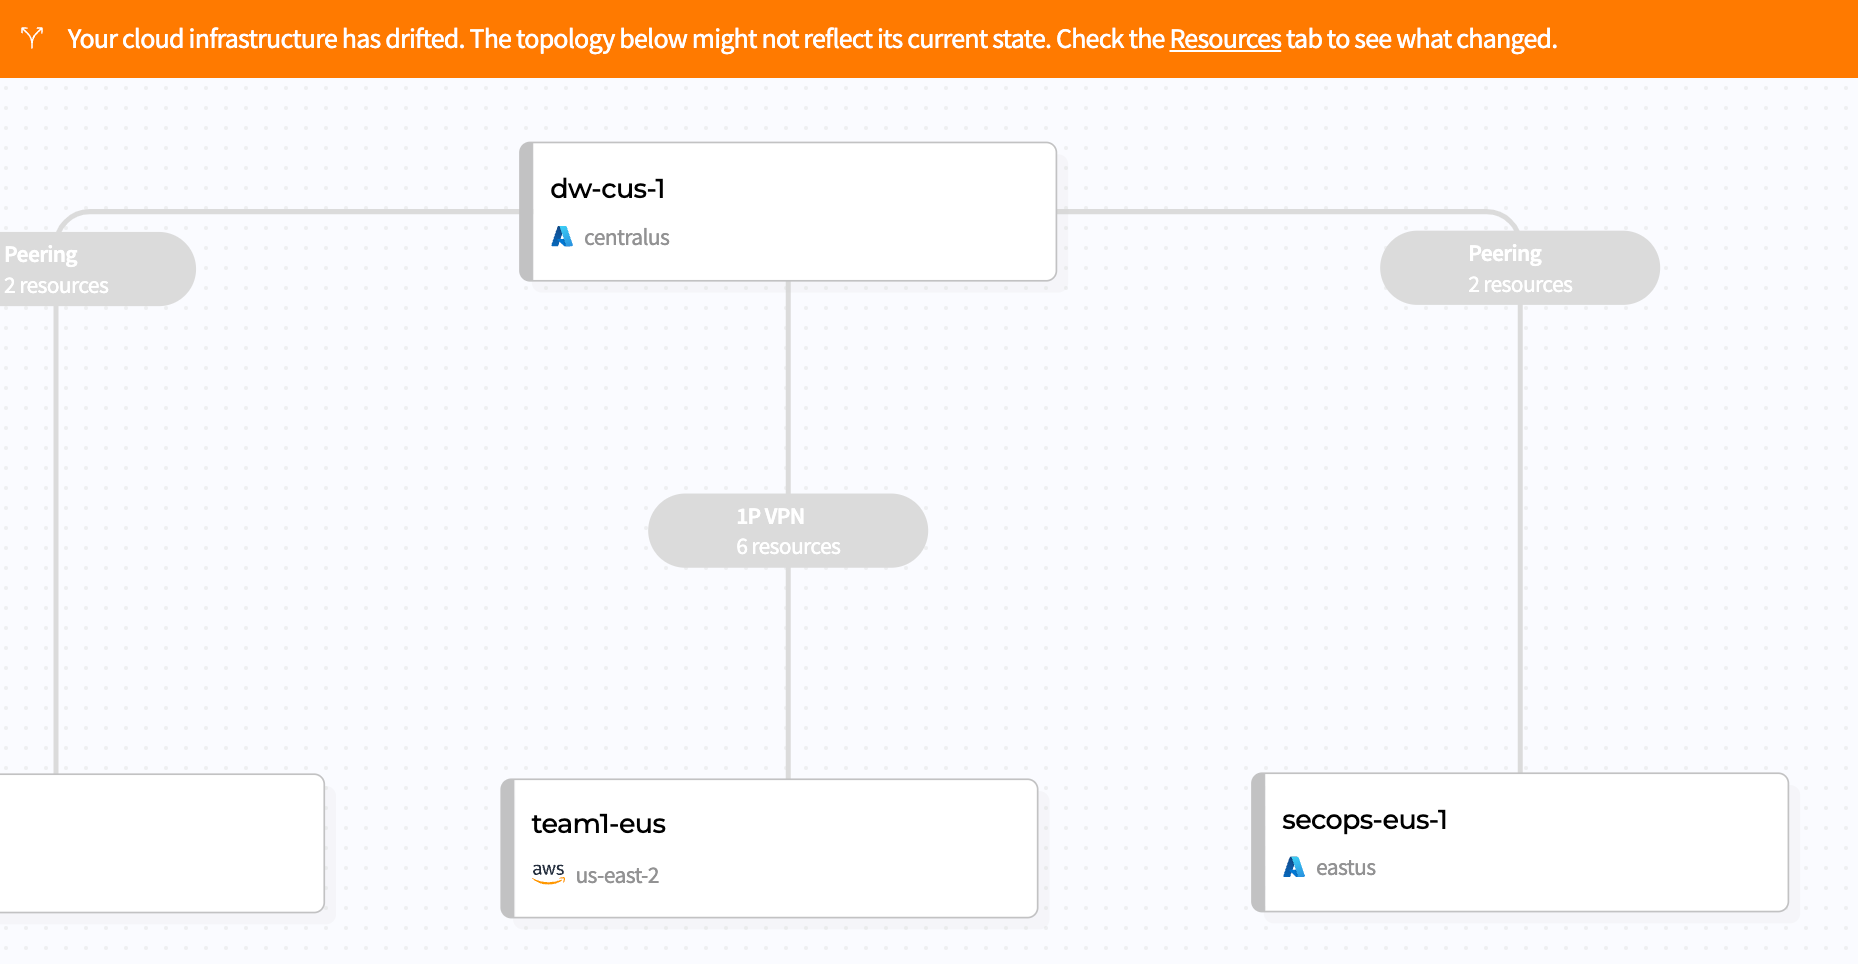
Once your network is deployed, Magic Cloud Networking monitors its configuration and health, enabling you to be confident that the security and connectivity you put in place yesterday is still in place today. It tracks the cloud resources it is responsible for, automatically reverting drift if they are changed out-of-band, while allowing you to manage other resources, like storage buckets and application servers, with other automation tools. And, as you change your network, Cloudflare takes care of route management, injecting and withdrawing routes globally across Cloudflare and all connected cloud provider networks.

Magic Cloud Networking is fully programmable via API, and can be integrated into existing automation toolchains.

The interface warns when cloud network infrastructure drifts from intent

Ready to start conquering cloud networking?

We are thrilled to introduce Magic Cloud Networking as another pivotal step to fulfilling the promise of the Connectivity Cloud. This marks our initial stride in empowering customers to seamlessly integrate Cloudflare with their public clouds to get securely connected, stay securely connected, and gain flexibility and cost savings as they go.

Join us on this journey for early access: learn more and sign up here.

Cloudflare customers can now use Microsoft Azure Data Transfer Routing Preference to enjoy lower data transfer costs

Post Syndicated from Deeksha Lamba original https://blog.cloudflare.com/discounted-egress-for-cloudflare-customers-from-microsoft-azure-is-now-available/

Cloudflare customers can now use Microsoft Azure Data Transfer Routing Preference to enjoy lower data transfer costs

Cloudflare customers can now use Microsoft Azure Data Transfer Routing Preference to enjoy lower data transfer costs

Today, we are excited to announce that Cloudflare customers can choose Microsoft Azure with a lower cost data transfer solution via the Microsoft Routing Preference service. Mutual customers can benefit from lower cost and predictable performance across our interconnected networks. Microsoft Azure has developed a seamless process to allow customers to choose this cost optimized routing solution.  We have customers using this new integration today and are excited to make this generally available to all our customers and prospects.

The power of interconnected networks

So how are we able to enable this great solution for our customers? The answer lies in our globally interconnected network.

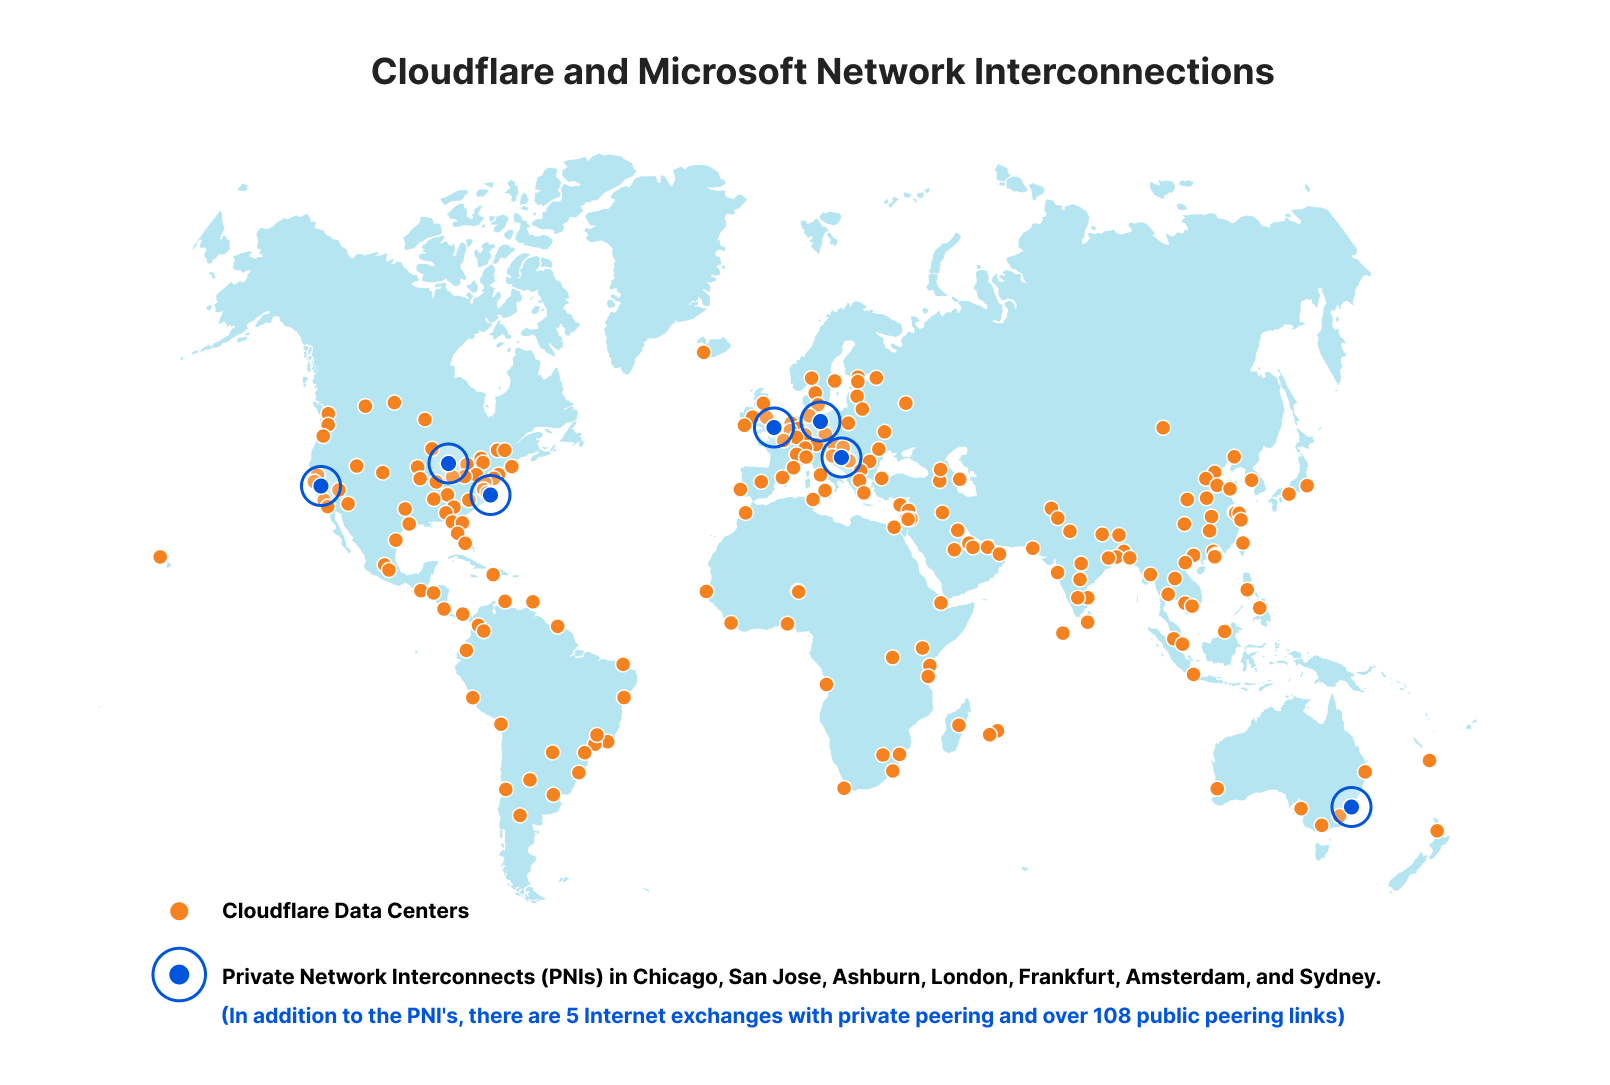
Cloudflare is one of the most interconnected networks in the world, peering with over 9,500 networks globally, including major ISPs, cloud providers, and enterprises. We currently interconnect with Azure through private or public peering across all major regions — including private interconnections at key locations (see below).

Private Network Interconnects typically occur within the same facility through a fiber optic cable between routers for the two networks; peered connections occur at Internet exchanges offering high performance and availability. We are actively working on expanding on this interconnectivity between Azure and Cloudflare for our customers.

In addition to the private interconnections, we also have five Internet exchanges with private peering, and over 108 public peering links with Azure

Cloudflare customers can now use Microsoft Azure Data Transfer Routing Preference to enjoy lower data transfer costs

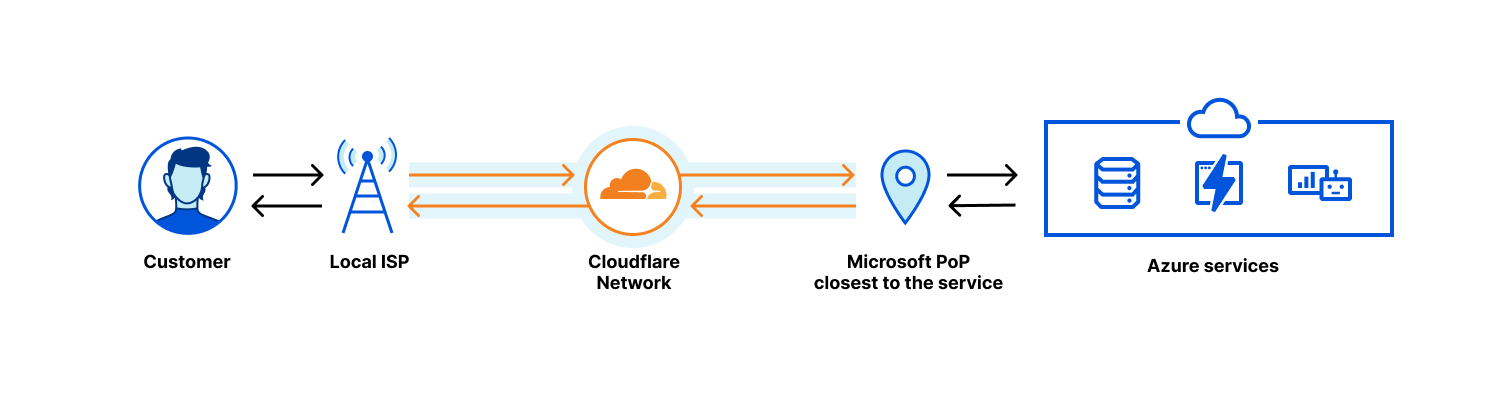
Wondering what this really means? Let’s look at an example. Say an Internet visitor is in Sydney and requests content from an origin that’s hosted in an Azure location in Chicago. When the visitor makes a request, Cloudflare automatically carries it to the Cloudflare data center in Sydney. The traffic is then routed over Cloudflare’s network all the way to Chicago where the origin is hosted on Azure. The request is then handed over to an Azure data center over our private interconnections.

On the way back (egress path), the request is handed over from Azure network to Cloudflare at the origin in Chicago via our private interconnection (without involving any ISP). Then it’s carried entirely over the Cloudflare network to Sydney and back to the visitor.

Cloudflare customers can now use Microsoft Azure Data Transfer Routing Preference to enjoy lower data transfer costs

Why does the Internet need this?

Customer choice. That’s an important ingredient to help build a better Internet for our customers — free of vendor lock-in, and with open Internet standards. We’ve worked with the Azure team to enable this interconnectivity, giving the customers the flexibility to choose multiple best-of-breed products without having to worry about high data transfer costs.

What is even more exciting is working with Microsoft, a company that shares our philosophy of promoting customer flexibility and helping customers resist vendor lock-in:

“Microsoft Azure is committed to offering services that make it easy to use offerings from industry leaders like Cloudflare – enabling choice to address customer’s business need.”
Jeff Cohen, Partner Group Program Manager for Azure Networking.

Easy for customers to get started

Cloudflare customers now have the option to leverage Azure routing preference and as a result use both platforms for their respective features and services offering the most secure and performant solution.

Most importantly customers can avail of this lower cost solution with just three simple steps.

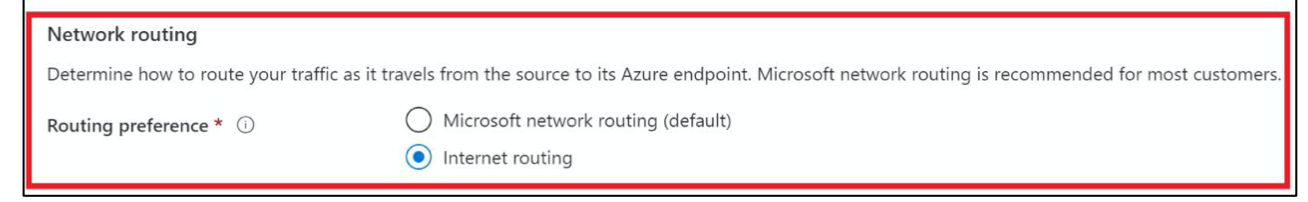
Step 1: Choose Internet routing on your Azure dashboard for origin in Azure storage:

Cloudflare customers can now use Microsoft Azure Data Transfer Routing Preference to enjoy lower data transfer costs

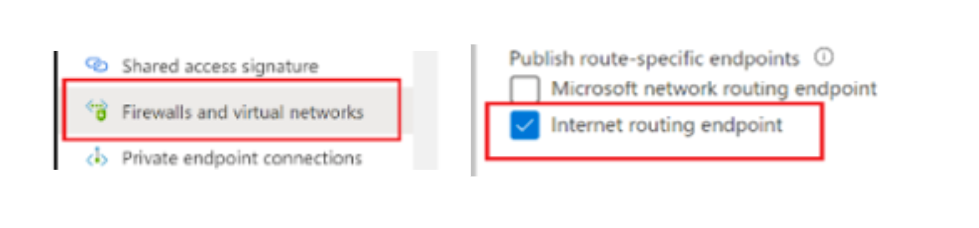
Step 2: Enable Internet routing on your Firewall and virtual network tab:

Cloudflare customers can now use Microsoft Azure Data Transfer Routing Preference to enjoy lower data transfer costs

Step 3: Enter your updated endpoint urls from Azure into your Cloudflare dashboard:

Cloudflare customers can now use Microsoft Azure Data Transfer Routing Preference to enjoy lower data transfer costs

Once enabled, the discounting is automatic and ongoing from the next monthly bill. Further details on the discounted rates can be found in Azure’s Bandwidth pricing.

A number of customers are already enjoying these benefits:

“Enabling cost-optimized egress by Cloudflare and Azure via Routing Preference from the Azure dashboard has been very smooth for us with minimal effort. Cloudflare was proactive in reaching out with its customer-centric approach.”
Joakim Jamte, Engineering Manager, Bannerflow

“Before taking advantage of the Routing Preference by Azure via Cloudflare, Egress fees were one of the key reasons that restricted us from having more multi-cloud solutions since it can be high and unpredictable at times as the traffic scales. Enabling Routing Preference on the Azure dashboard was quick and easy. It was a one-and-done effort and we get discounted Egress rates on every Azure bill.”
Darin MacRae, Chief Architect / Cloud Computing, MyRadar.com

“Along with Cloudflare’s excellent security features and high performing CDN, the data transfer rates from Azure’s Routing Preference enabled by Cloudflare make the offer very compelling. Enabling and receiving the discount was very easy and helped us optimize our investment without any effort.”
Arthur Roodenburg, CIO, Act-3D B.V.

We’re pleased today to offer this benefit to all Cloudflare customers. If you are interested in taking advantage of Routing Preference please reach out.