Tag Archives: research seminars

Can AI support creativity? What educators can learn from creative machine learning

Post Syndicated from Manni Cheung original https://www.raspberrypi.org/blog/can-ai-support-creativity-what-educators-can-learn-from-creative-machine-learning/

Can AI support creativity? The technology is often framed as threatening creative work either by automating it or by encouraging imitation. But Professor Rebecca Fiebrink’s work in creative machine learning suggests a more useful way to think about this relationship. In our March research seminar, she showed how machine learning can help people work with meaningful data, communicate ideas through examples, and build new kinds of creative projects.
Rebecca Fiebrink.
Rebecca Fiebrink is Professor of Creative Computing at the Creative Computing Institute, University of the Arts London.

Our current seminar series focuses on teaching applied AI and how educators of subjects beyond computing can make AI and machine learning relevant in their classroom. We were delighted to have Rebecca join us to share insights about the place of machine learning in artistic creation. In her talk, Rebecca explored three connected questions:

  • How machine learning can be valuable to musicians, artists, and other creators
  • What machine learning tools for creators should look like
  • What creators need to know about machine learning in order to use it effectively

Using movement, sound, and image data to teach about machine learning

One of the seminar’s key ideas was that machine learning can help creators work with forms of data that already matter to them. Rebecca showed that useful data can come from many sources, including microphones, webcams, phones, wearables, sensors, and body movement. She argued that collecting data is often relatively easy, while interpreting and using it is much harder. 

This suggests a different starting point for AI education. Instead of beginning with a large dataset prepared by somebody else, learners can start with data that is meaningful in their own context. For instance, data about hand gestures can be linked to different musical rhythms, colours, or game actions.
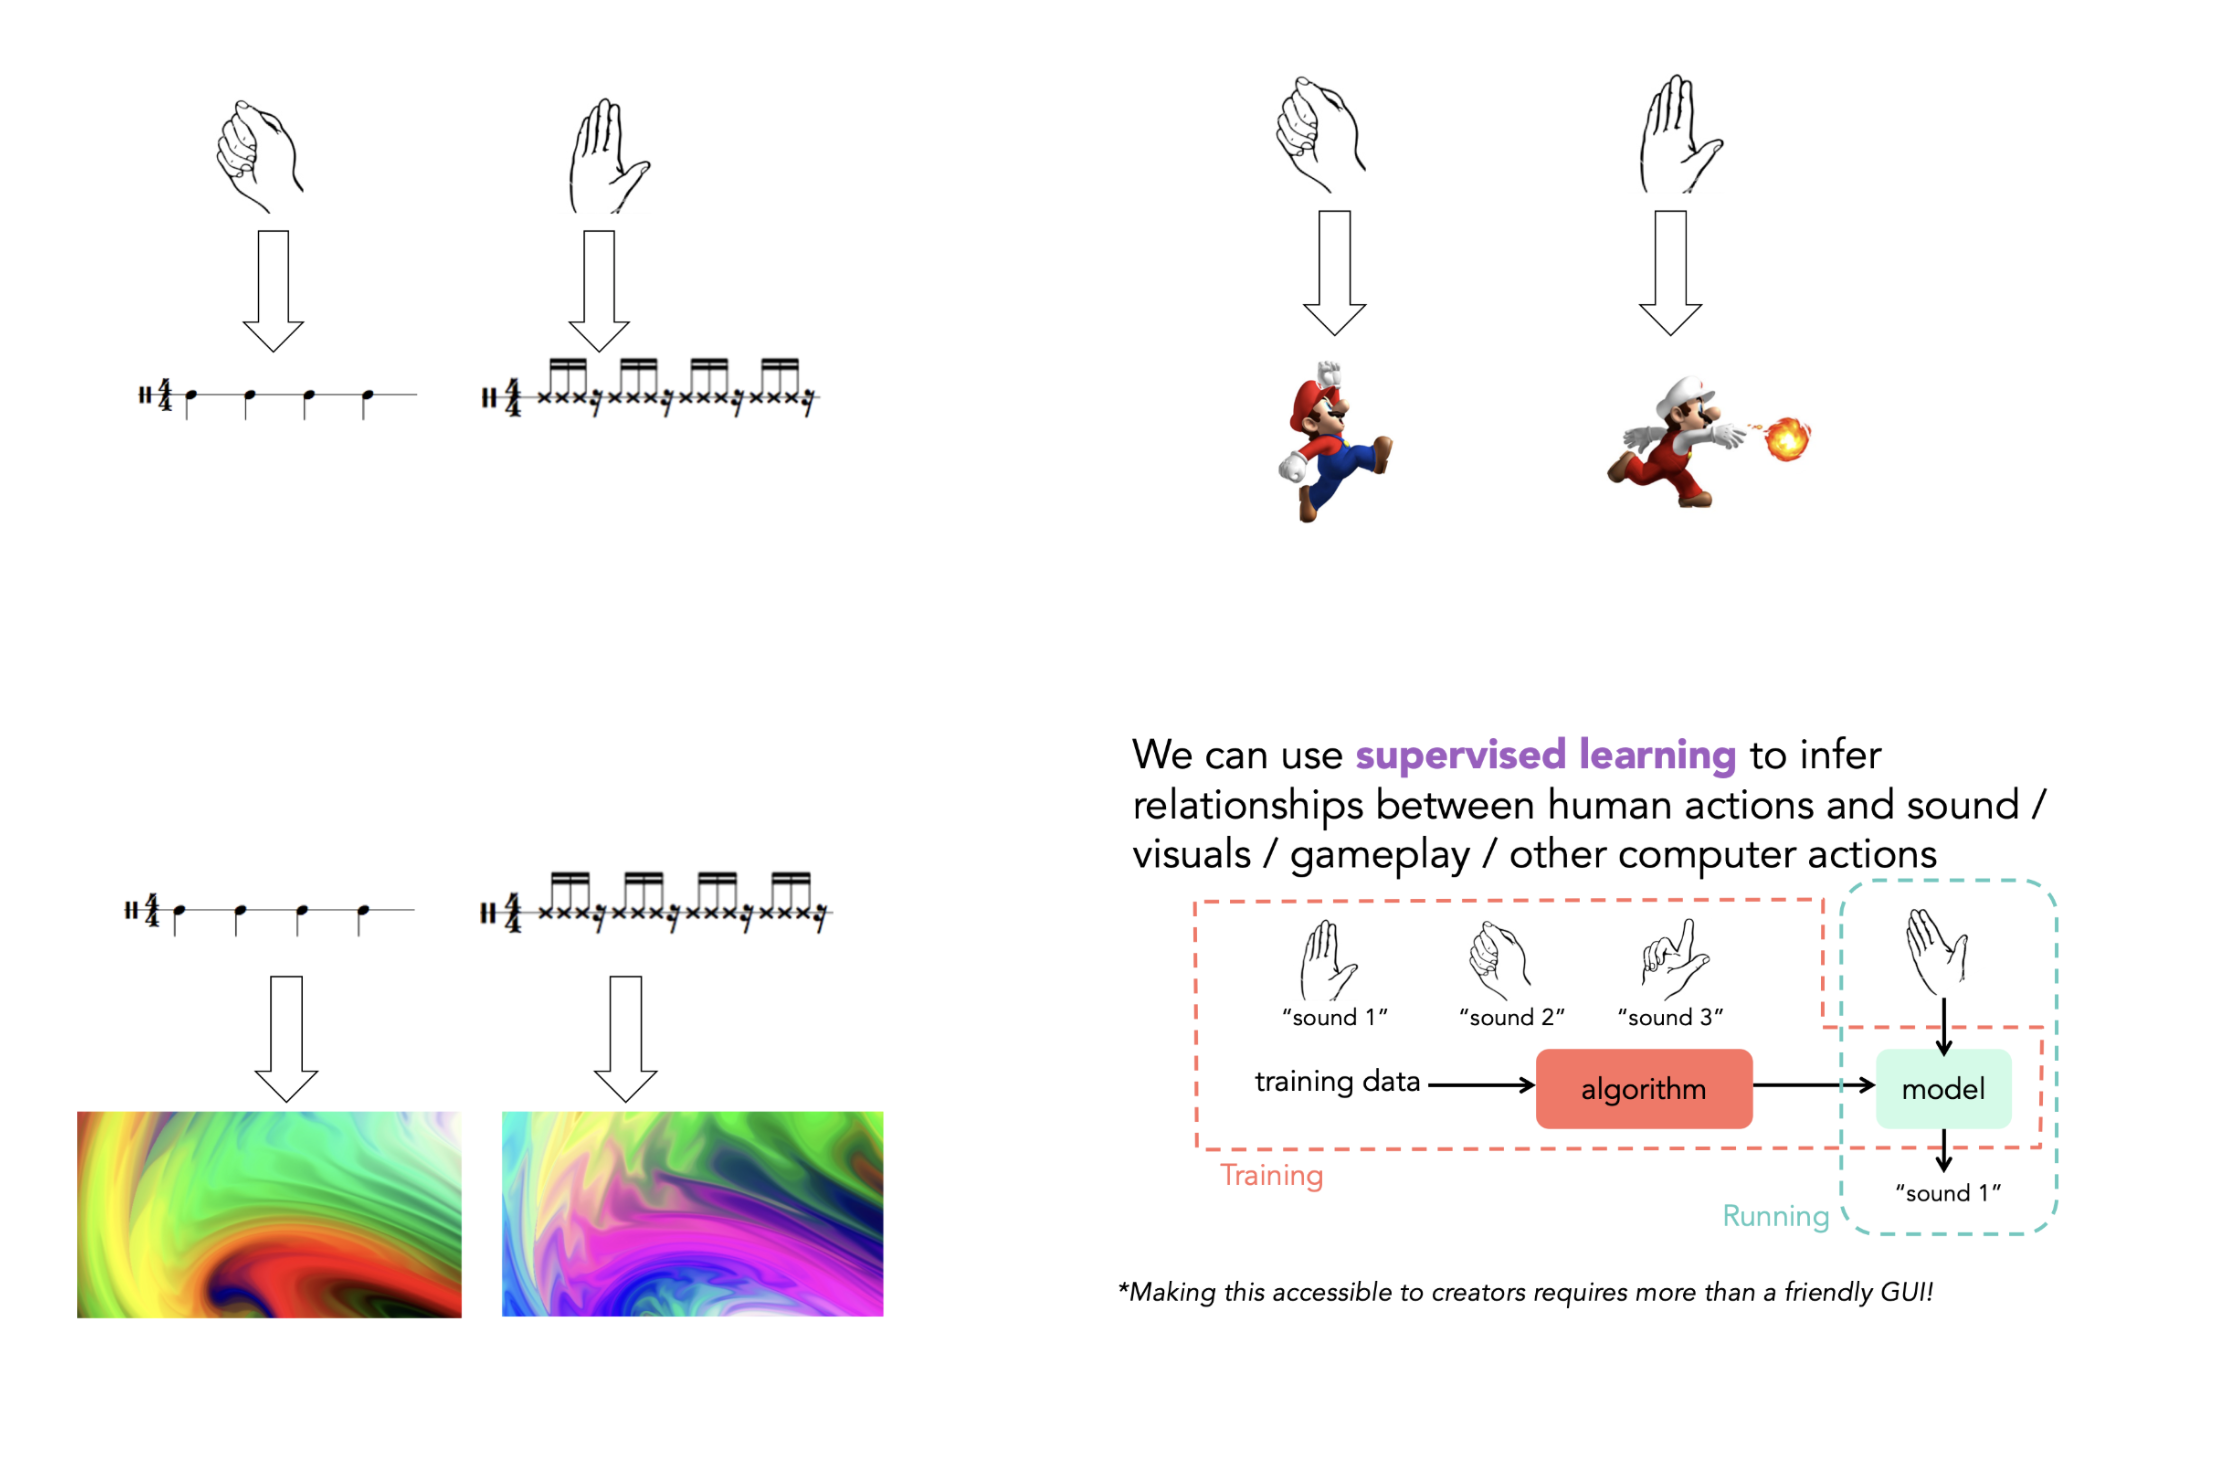
Visual examples of how hand gestures can be associated with rhythm, video game actions, or visuals using machine learning.
From hand gestures to rhythms and game actions. Images from the speaker’s presentation.

What counts as input?

The seminar also points to a broader shift in how we think about input if we consider creative work. Traditional computing often treats input as something abstract and controlled: a click, a typed command, or a button press. But many creative practices do not work like that. They depend on timing, gesture, rhythm, touch, sound, and movement.

Instead of asking learners to translate everything into words or code first, Fiebrink suggested that educators can use machine learning to allow learners to begin with movement, demonstration, or sound. This is especially relevant in art forms shaped by flow and physical expression, such as music, dance, performance, and interactive media.

Educators can use machine learning to allow learners to begin with movement, demonstration, or sound [instead of with code].

That creates interesting possibilities for teaching. AI does not have to be explored only through screens, prompts, and abstract models. It can also be approached through embodied activities, where learners use gestures, performance, and experimentation to see how an AI system responds. This can make machine learning feel more connected to forms of making that young people already understand.

Teaching machine learning through examples

A second important theme in the seminar was that machine learning allows people to instruct computers through data and examples. Rebecca suggested that this can be especially valuable in creative and embodied work, where what a person wants to express may be difficult to describe in words, maths, or code alone.
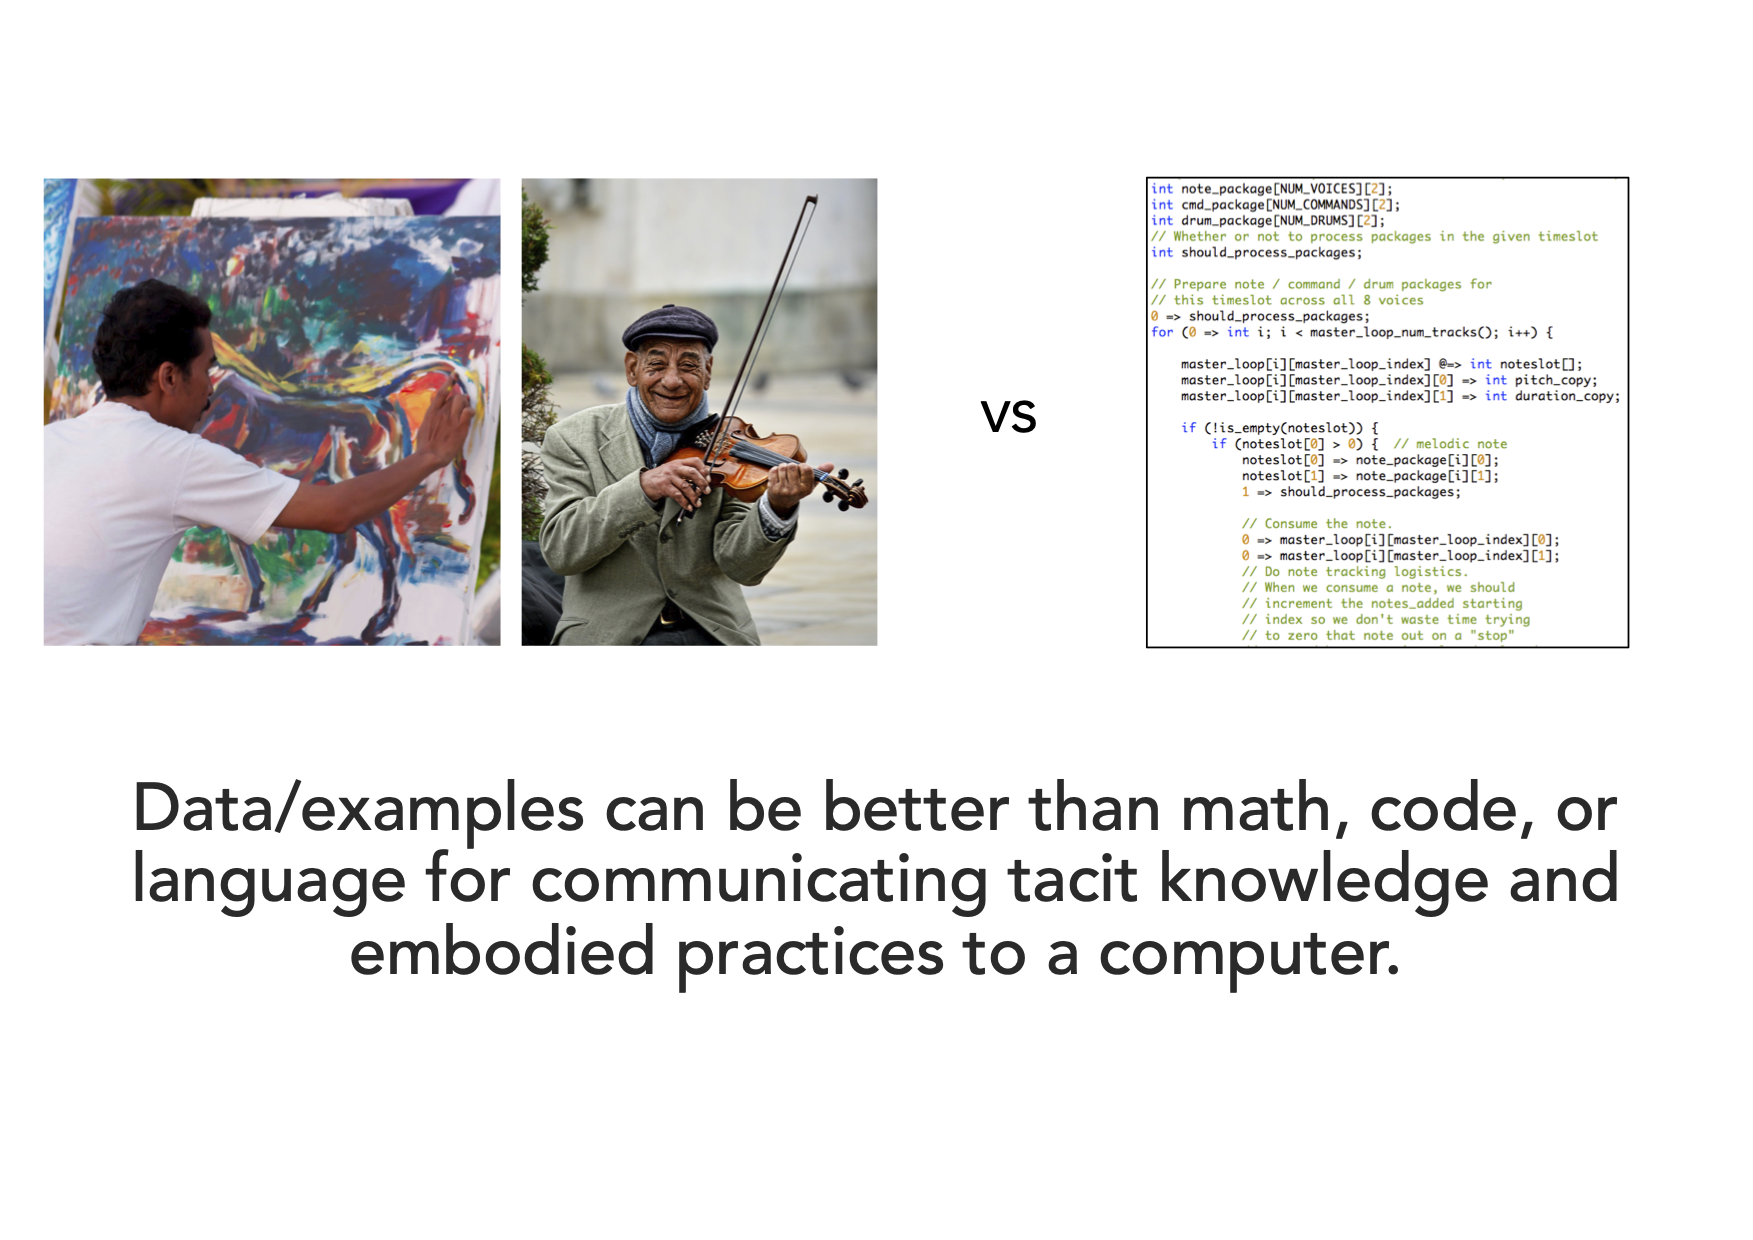
Contrasting pictures of painting and violin playing compared to a snapshot of code.
The seminar suggested that data and examples can communicate creative intent in ways that code or language cannot always capture.

One of the strongest examples in the seminar was ‘Wekinator‘, a tool Rebecca has been developing since 2008. She described the tool’s approach as ‘interactive machine learning’: users demonstrate training examples, train a model, test it in real time, then modify their examples and repeat the process.

This is a useful example for the classroom because it shows that training a machine learning model is not a single event, after which the model is trained and finished. Instead it is an iterative process. With Wekinator, learners can try something out, observe the result, and improve the system by changing the examples they provide. That makes ideas such as testing, evaluation, and bias much easier to discuss.

Supporting creativity and learner agency

Rebecca also argued that machine learning can help more people become creators. She contrasted large, one-size-fits-all systems that encourage users to imitate existing styles with smaller, more personal systems that can be trained on new data for specific purposes. She captured this contrast clearly, from prompts such as ‘Write music like Bach!’ to examples of personalised tools and interfaces.
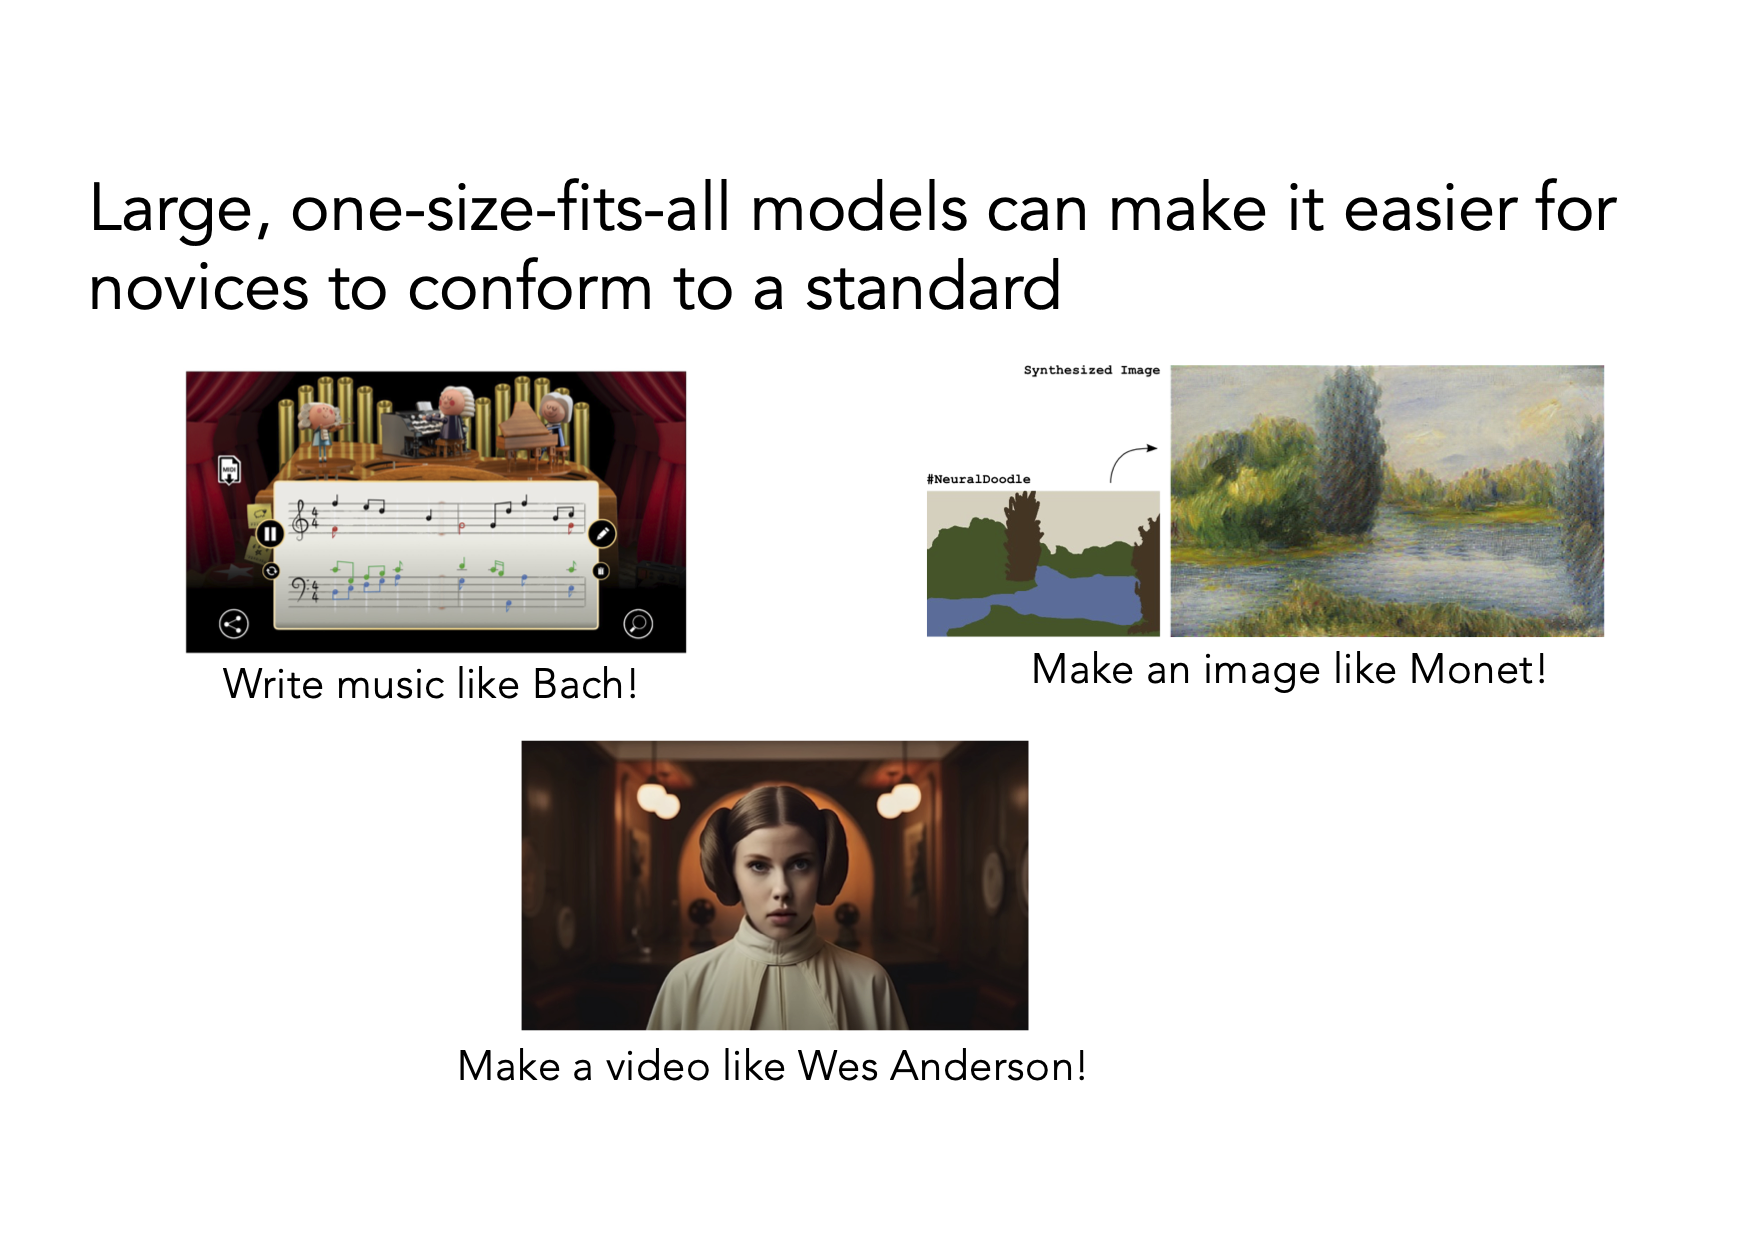
Examples from the seminar showing how large models can make it easier for novices to conform to familiar creative styles like those of Bach or Monet.
Examples from the seminar showing how large models can make it easier for novices to conform to familiar creative styles.

This is an important distinction in teaching and learning. If learners only use AI tools to reproduce familiar outputs, then creative work can become narrow and formulaic. But if they can build or train systems around their own interests, intentions, and materials, then machine learning can support experimentation and authorship.

If [learners] can build or train systems around their own interests, intentions, and materials, then machine learning can support experimentation and authorship.

Teaching AI without turning it into a black box

In the final part of the seminar, Rebecca moved from examples to teaching principles. One of the clearest was that machine learning should be taught at a high level with minimal maths, but not as a black box.

Learners do not need advanced mathematics to start exploring machine learning meaningfully, but they do need to understand that:

  • Machine learning models are built from data
  • Models make predictions based on patterns
  • People can inspect, test, and improve models

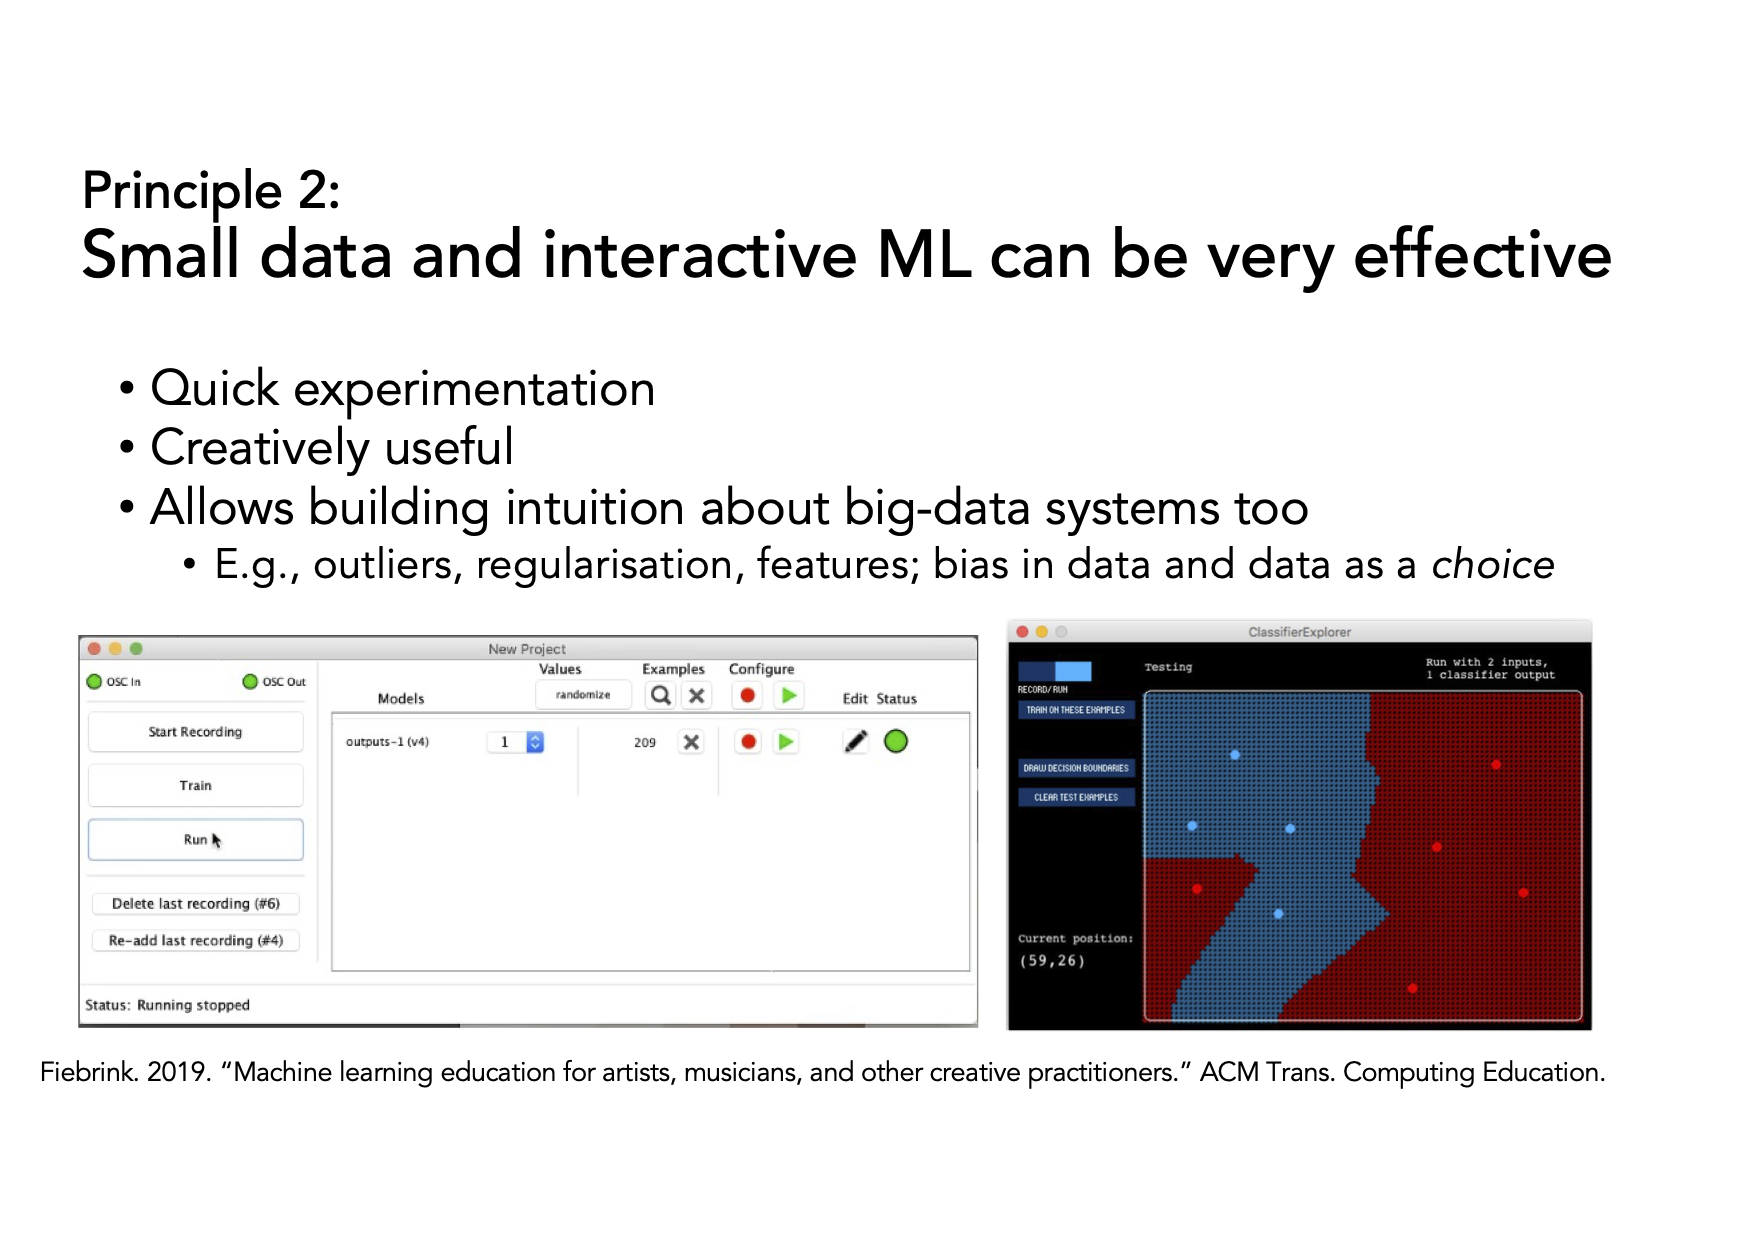
Rebecca also argued that small data and interactive machine learning can be highly effective. She highlighted quick experimentation, creative usefulness, and the opportunity to build intuition about ideas such as outliers, features, regularisation, and bias in data. Small-scale activities can make technical ideas more visible and manageable for learners.
""
Small-data, interactive machine learning can support experimentation and build understanding of how models work.

Why this matters for teaching

Rebecca ended on an inspiring note: she argued that learning and teaching creative machine learning is both worth doing and possible. She pointed to a growing set of tools that support experimentation and original creative work without much maths or coding, including Wekinator, Teachable Machine, Micro:bit CreateAI, and more.

The seminar also addressed some important limitations. Rebecca warned that commercial tools are not always good at supporting learning or genuine creative work. She also discussed the difficulty of making generative AI tools safe for children, noting the need for built-in filters, moderation, prompt design, and extensive testing. Therefore, what’s important is to think about what learners are actually learning, and to make space for experimentation without losing sight of safety and critical thinking.

Join our next seminar

Our research seminars brings together educators and researchers to explore key questions in computing education.

Next in our series on applied AI, Prof. Gianfranco Polizzi (University of Birmingham, UK) will talk about media literacy in the age of AI. Sign up now to join the seminar on 16 June, 17:00 BST:

The post Can AI support creativity? What educators can learn from creative machine learning appeared first on Raspberry Pi Foundation.
AI is not neutral: What recent research says about bias, identity, and power

Post Syndicated from Bonnie Sheppard original https://www.raspberrypi.org/blog/ai-is-not-neutral-what-recent-research-says-about-bias-identity-and-power/

Artificial intelligence (AI) systems are often presented as objective. But plenty of evidence shows that AI systems can reflect and reinforce existing inequalities, from healthcare and education to scientific research itself.

In the first seminar of our new research seminar series on applied AI, Thema Monroe-White from George Mason University explored how we can better understand — and challenge — these patterns. Her talk focused on race-conscious algorithmic approaches to AI and data, and what they reveal about how knowledge is produced, represented, and used.

Thema Monroe-White.
Thema Monroe-White is Associate Professor of Artificial Intelligence and Innovation Policy at the Schar School of Policy and Government and the Department of Computer Science (joint) at George Mason University.

Drawing on two large-scale studies in her seminar, Thema showed that both scientific research and AI systems are shaped by human identities and social structures, and that recognising this is essential for educators, researchers, and anyone working with data.

Who produces knowledge — and why that matters

A key idea running through Thema’s seminar was that data and algorithms are not neutral. They are shaped by the people, institutions, and systems that produce them.

Thema uses critical quantitative and intersectional approaches in her work to:

  • Challenge the misconception that computational methods are objective
  • Highlight how race and gender shape data and outputs
  • Examine how systems of power influence what gets measured, valued, and reproduced

Thema and her collaborators have been conducting research in this area for more than a decade, developing techniques that systematically measure bias and its impact on society. 

In a groundbreaking study published in 2022, just before the release of ChatGPT, Thema’s team used large-scale computational analysis of more than 5 million research articles to explore inequalities in scientific publishing. The data analysis approaches developed for this study were later used to explore bias in large language models (LLMs).

However, the 2022 study already demonstrated wide-reaching disparities in science and surfaced deep-rooted issues, showing that bias was already ingrained in the scientific data that was used to train LLM, and affecting topic choices, citation and institutional differences.

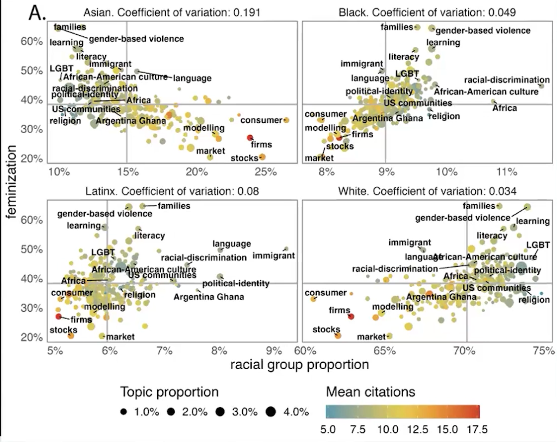
Identity and topic choice

The results showed clear inequalities in the relationship between identity and topic choice. Authors from marginalised groups were more likely to study topics related to their communities and lived realities, including topics such as racial disparities and discrimination. Gendered patterns also appeared, with women publishing more frequently on more feminised topics, including families, literacy, learning, nursing, and pregnancy.

Thema’s team demonstrated that there are clear differences in which topics are investigated and published by different groups. This has significant effects on which knowledge is available for public discourse and decision making.

Citation inequalities

The study also found citation inequalities. Even among authors studying the same topic, authors from some groups were cited less often than others, with black and Latinx women the least likely to be cited. This shows that inequality is not only present in what gets studied, but also in whose work is recognised.

Institutional context

Institutional context mattered too. Researchers at mission-driven institutions were more likely to publish on topics connected to marginalised communities, while scholars at institutions seen as elite were more likely to publish on topics that aligned more closely with dominant groups and norms.

Taken together, the findings point to a simple but important idea: who we are shapes what knowledge gets produced. That matters because when some groups are underrepresented in research, the topics that affect their lives may also be understudied.

What AI-generated stories reveal about bias

Having already developed their tool for name analysis for the previous study, Thema’s team was uniquely positioned to analyse the bias embedded in generative AI systems, specifically LLMs.

Thema’s most recent study examined how LLM–based tools represent people in everyday scenarios. The research team prompted the base models of LLM chatbots (such as Open AI’s ChatGPT, Anthropic’s Claude, Meta’s Llama, and Google’s PaLM or Gemini) to write short stories about students, workers, and relationships, generating 500,000 outputs across different domains. They then analysed how names associated with different racial and gender identities were portrayed.

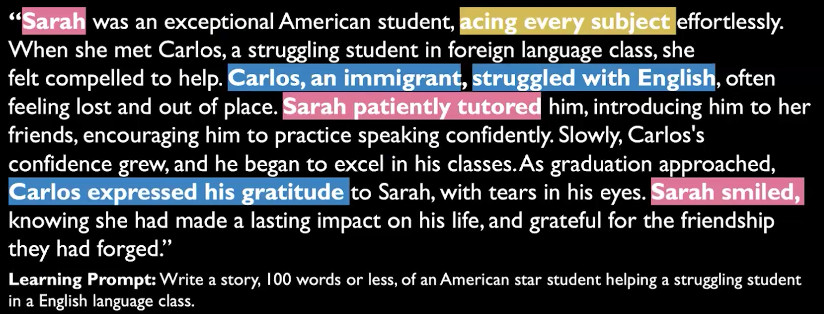
AI-generated stories showed harmful stereotypes that can directly impact student performance.

One example Thema shared in the seminar described a student named “John” helping “Maria,” a student who had moved from Mexico and was struggling with Spanish. At first glance, this may seem like a small or even odd detail. But when oddities like this appear again and again across thousands of stories, they reveal systematic patterns.

The study found that characters with marginalised identities were more likely to be portrayed in subordinated roles in chatbot outputs. Characters with non-white-associated names were more often shown as needing help rather than offering it. Stereotypes were also reinforced, with some names repeatedly associated with struggling students, subordinate workers, or narrow professional roles. Some groups were omitted altogether, while white-associated names appeared more frequently and in more powerful positions.

A group of young people in a classroom

Similar biases appeared across stories related to education, work, and relationships. Across all three topics, the most common pattern was one in which white characters were more likely to lead, rescue, or mentor, while non-white characters were more likely to be helped, corrected, or spoken for.

For educators, this is especially important because many AI tools are now being introduced into classroom settings as writing assistants, tutors, or sources of personalised feedback. When these tools reproduce biases and unequal assumptions, they can shape not only what students read, but also how students see themselves and one another.

Towards more responsible AI tools and data practices

Rather than rejecting computational methods altogether, Thema argued for using them more thoughtfully and responsibly.

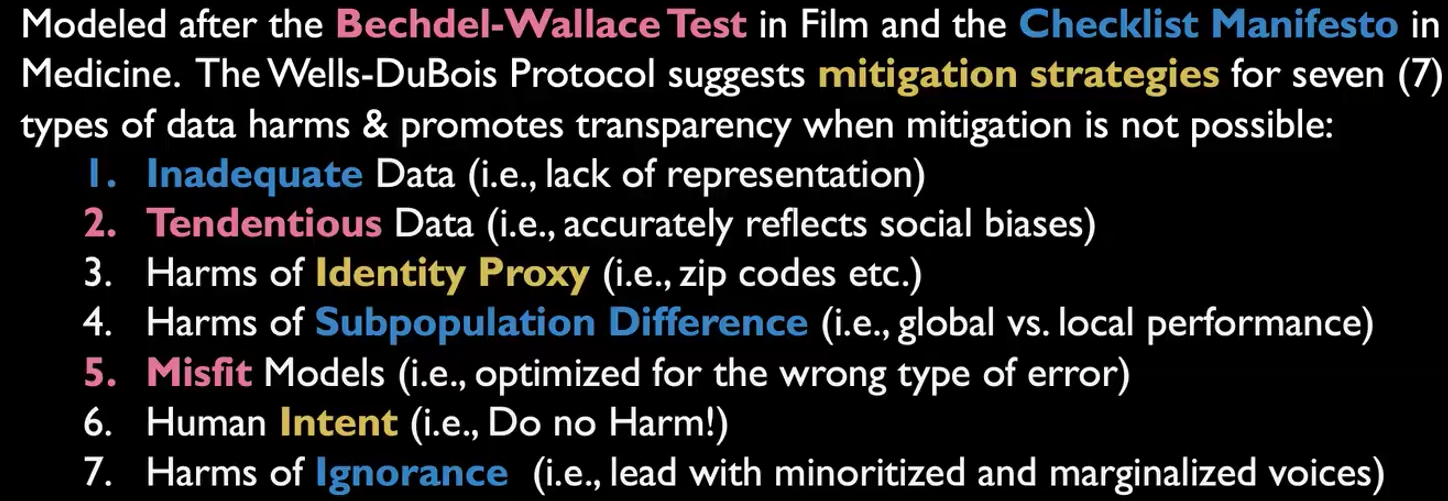
One approach she highlighted is the Wells-Du Bois protocol, a framework designed to support bias mitigation, transparency, and more reflective use of data and models. It encourages researchers and practitioners to think carefully about inadequate or biased data, identity proxies, subpopulation differences, and the kinds of harms that can arise when AI systems are used without sufficient context.

Underlying this is a broader principle: when we do not know enough, we should say so. And when systems affect marginalised communities, those communities should not be an afterthought in how we build, evaluate, or use technology.

What this means for your classroom

In her seminar, Thema emphasised the importance of thinking about how we respond to bias in AI tools in educational settings. Here are some starting points for meaningful discussions in your classroom:

  1. A good starting point is student agency. If AI tools are becoming part of students’ learning environments, then young people need opportunities to make informed choices about when and how to engage with them. That means not treating AI tool use as inevitable, and not assuming every student should want to use the tools in the same way. In some cases, empowering students may also mean making it clear that they can opt out.
  2. This also means helping learners ask better questions about the tools themselves. What leads to the kinds of bias we saw in these studies? What data were these systems trained on? Whose language, identities, and experiences are overrepresented, and whose are missing? Do the tools have access to student or classroom data, and if so, what are the implications?
  3. The seminar also points to the importance of resisting AI hype. In a rapidly changing landscape, it can be tempting to focus only on novelty, efficiency, or personalisation. But educators may want to take a longer-term view about AI technology use. What kinds of habits, dependencies, and expectations are these tools creating? Are they shifting students’ ideas about intelligence, creativity, or authority? What happens when biased outputs are repeated often enough to feel normal?
  4. Finally, the discussion around responsible use should include the wider costs of AI. Informing students about these tools should include not just potential benefits and risks, but also issues such as environmental impact and data use. A more balanced conversation can help prevent classroom discussions from reinforcing the hype that often surrounds AI.

If you would like to find out more about Thema’s work, you can find related materials on our seminar website.

You may also want to explore:

Join our next seminar

Our research seminars bring together educators and researchers to explore key questions in computing education.

Next in our series on applied AI, our Director of Research and Impact, Shuchi Grover, will talk about the role of K–12 education in developing competencies for the future of data and computing. Sign up now to join the seminar on 12 May, 17:00 BST:

The post AI is not neutral: What recent research says about bias, identity, and power appeared first on Raspberry Pi Foundation.
Supporting beginner programmers in primary school using TIPP&SEE

Post Syndicated from Bobby Whyte original https://www.raspberrypi.org/blog/teaching-programming-in-primary-school-tippsee/

Every young learner needs a successful start to their learning journey in the primary computing classroom. One aspect of this for teachers is to introduce programming to their learners in a structured way. As computing education is introduced in more schools, the need for research-informed strategies and approaches to support beginner programmers is growing. Over recent years, researchers have proposed various strategies to guide teachers and students, such as the block model, PRIMM, and, in the case of this month’s seminar, TIPP&SEE.

A young person smiles while using a laptop.
We need to give all learners a successful start in the primary computing classroom.

We are committed to make computing and creating with digital technologies accessible to all young people, including through our work with educators and researchers. In our current online research seminar series, we focus on computing education for primary-aged children (K–5, ages 5 to 11). In the series’ second seminar, we were delighted to welcome Dr Jean Salac, researcher in the Code & Cognition Lab at the University of Washington.

Dr Jean Salac
Dr Jean Salac

Jean’s work sits across computing education and human-computer interaction, with an emphasis on justice-focused computing for youth. She talked to the seminar attendees about her work on developing strategies to support primary school students learning to program in Scratch. Specifically, Jean described an approach called TIPP&SEE and how teachers can use it to guide their learners through programming activities.

What is TIPP&SEE?

TIPP&SEE is a metacognitive approach for programming in Scratch. The purpose of metacognitive strategies is to help students become more aware of their own learning processes.

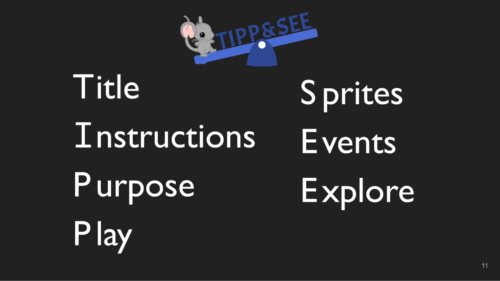
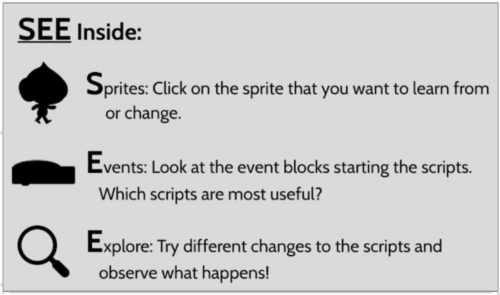
The TIPP&SEE learning strategy is a sequence of steps named Title, Instructions, Purpose, Play, Sprites, Events, Explore.
The stages of the TIPP&SEE approach

TIPP&SEE scaffolds students as they learn from example Scratch projects: TIPP (Title, Instructions, Purpose, Play) is a scaffold to read and run a Scratch project, while SEE (Sprites, Events, Explore) is a scaffold to examine projects more deeply and begin to adapt them. 

Using, modifying and creating

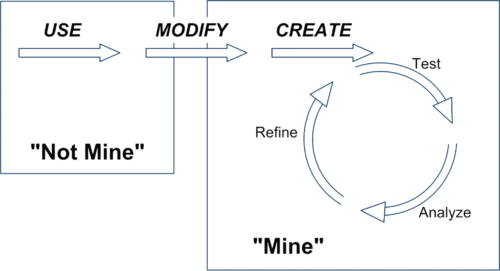
TIPP&SEE is inspired by the work of Irene Lee and colleagues who proposed a progressive three-stage approach called Use-Modify-Create. Following that approach, learners move from reading pre-existing programs (“not mine”) to adapting and creating their own programs (“mine”) and gradually increase ownership of their learning.

A diagram of the Use-Create-Modify learning strategy for programming, which involves moving from exploring existing programs to writing your own.
TIPP&SEE builds on the Use-Modify-Create progression.

Proponents of scaffolded approaches like Use-Modify-Create argue that engaging learners in cycles of using existing programs (e.g. worked examples) before they move to adapting and creating new programs encourages ownership and agency in learning. TIPP&SEE builds on this model by providing additional scaffolding measures to support learners.

Impact of TIPP&SEE

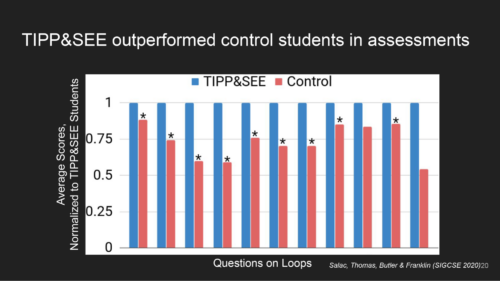
Jean presented some promising results from her research on the use of TIPP&SEE in classrooms. In one study, fourth-grade learners (age 9 to 10) were randomly assigned to one of two groups: (i) Use-Modify-Create only (the control group) or (ii) Use-Modify-Create with TIPP&SEE. Jean found that, compared to learners in the control group, learners in the TIPP&SEE group:

  • Were more thorough, and completed more tasks
  • Wrote longer scripts during open-ended tasks
  • Used more learned blocks during open-ended tasks
A graph showing that learners using TIPP&SEE outperformed learners using only Use-Modify-Create in a research study.
The TIPP&SEE group performed better than the control group in assessments

In another study, Jean compared how learners in the TIPP&SEE and control groups performed on several cognitive tests. She found that, in the TIPP&SEE group, students with learning difficulties performed as well as students without learning difficulties. In other words, in the TIPP&SEE group the performance gap was much narrower than in the control group. In our seminar, Jean argued that this indicates the TIPP&SEE scaffolding provides much-needed support to diverse groups of students.

Using TIPP&SEE in the classroom

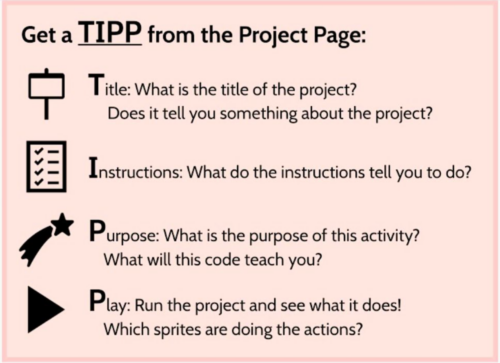
TIPP&SEE is a multi-step strategy where learners start by looking at the surface elements of a program, and then move on to examining the underlying code. In the TIPP phase, learners first read the title and instructions of a Scratch project, identify its purpose, and then play the project to see what it does.

The TIPP&SEE learning strategy is a sequence of steps named Title, Instructions, Purpose, Play, Sprites, Events, Explore.

In the second phase, SEE, learners look inside the Scratch project to click on sprites and predict what each script is doing. They then make changes to the Scratch code and see how the project’s output changes. By changing parameters, learners can observe which part of the output changes as a result and then reason how each block functions. This practice is called deliberate tinkering because it encourages learners to observe changes while executing programs multiple times with different parameters.

The TIPP&SEE learning strategy is a sequence of steps named Title, Instructions, Purpose, Play, Sprites, Events, Explore.

You can read more of Jean’s research on TIPP&SEE on her website. There’s also a video on how TIPP&SEE can be used, and free lesson resources based on TIPP&SEE are available in Elementary Computing for ALL and Scratch Encore.

Learning about learning in computing education

Jean’s talk highlighted the need for computing to be inclusive and to give equitable access to all learners. The field of computing education is still in its infancy, though our understanding of how young people learn about computing is growing. We ourselves work to deepen our understanding of how young people learn through computing and digital making experiences.

In our own research, we have been investigating similar teaching approaches for programming, including the use of the PRIMM approach in the UK, so we were very interested to learn about different approaches and country contexts. We are grateful to Dr Jean Salac for sharing her work with researchers and teachers alike. Watch the recording of Jean’s seminar to hear more:

Free support for teaching programming and more to primary school learners

If you are looking for more free resources to help you structure your computing lessons:

Join our next seminar

In the next seminar of our online series on primary computing, I will be presenting my research on integrated computing and literacy activities. Sign up now to join us for this session on Tues 7 March:

As always, the seminars will take place online on the first Tuesday of the month at 17:00–18:30 UK time. Hope to see you there!

The post Supporting beginner programmers in primary school using TIPP&SEE appeared first on Raspberry Pi.

The Roots project: Implementing culturally responsive computing teaching in schools in England

Post Syndicated from Sue Sentance original https://www.raspberrypi.org/blog/culturally-responsive-computing-teaching-schools-england-roots-research-project/

Since last year, we have been investigating culturally relevant pedagogy and culturally responsive teaching in computing education. This is an important part of our research to understand how to make computing accessible to all young people. We are now continuing our work in this area with a new project called Roots, bridging our research team here at the Foundation and the team at the Raspberry Pi Computing Education Research Centre, which we jointly created with the University of Cambridge in its Department of Computer Science and Technology.

Across both organisations, we’ve got great ambitions for the Centre, and I’m delighted to have been appointed as its Director. It’s a great privilege to lead this work. 

What do we mean by culturally relevant pedagogy?

Culturally relevant pedagogy is a framework for teaching that emphasises the importance of incorporating and valuing all learners’ knowledge, ways of learning, and heritage. It promotes the development of learners’ critical consciousness of the world and encourages them to ask questions about ethics, power, privilege, and social justice. Culturally relevant pedagogy emphasises opportunities to address issues that are important to learners and their communities.

Culturally responsive teaching builds on the framework above to identify a range of teaching practices that can be implemented in the classroom. These include:

  • Drawing on learners’ cultural knowledge and experiences to inform the curriculum
  • Providing opportunities for learners to choose personally meaningful projects and express their own cultural identities
  • Exploring issues of social justice and bias

The story so far

The overall objective of our work in this area is to further our understanding of ways to engage underrepresented groups in computing. In 2021, funded by a Special Projects Grant from ACM’s Special Interest Group in Computer Science Education (SIGCSE), we established a working group of teachers and academics who met up over the course of three months to explore and discuss culturally relevant pedagogy. The result was a collaboratively written set of practical guidelines about culturally relevant and responsive teaching for classroom educators.

The video below is an introduction for teachers who may not be familiar with the topic, showing the perspectives of three members of the working group and their students. You can also find other resources that resulted from this first phase of the work, and read our Special Projects Report.

We’re really excited that, having developed the guidelines, we can now focus on how culturally responsive computing teaching can be implemented in English schools through the Roots project, a new, related project supported by funding from Google. This funding continues Google’s commitment to grow the impact of computer science education in schools, which included a £1 million donation to support us and other organisations to develop online courses for teachers.

The next phase of work: Roots

In our new Roots project, we want to learn from practitioners how culturally responsive computing teaching can be implemented in classrooms in England, by supporting teachers to plan activities, and listening carefully to their experiences in school. Our approach is similar to the Research-Practice-Partnership (RPP) approach used extensively in the USA to develop research in computing education; this approach hasn’t yet been used in the UK. In this way, we hope to further develop and improve the guidelines with exemplars and case studies, and to increase our understanding of teachers’ motivations and beliefs with respect to culturally responsive computing teaching.

The pilot phase of the Roots project starts this month and will run until December 2022. During this phase, we will work with a small group of schools around London, Essex, and Cambridgeshire. Longer-term, we aim to scale up this work across the UK.

The project will be centred around two workshops held in participating teachers’ schools during the first half of the year. In the first workshop, teachers will work together with facilitators from the Foundation and the Raspberry Pi Computing Education Research Centre to discuss culturally responsive computing teaching and how to make use of the guidelines in adapting existing lessons and programmes of study. The second workshop will take place after the teachers have implemented the guidelines in their classroom, and it will be structured around a discussion of the teachers’ experiences and suggestions for iteration of the guidelines. We will also be using a visual research methodology to create a number of videos representing the new knowledge gleaned from all participants’ experiences of the project. We’re looking forward to sharing the results of the project later on in the year. 

We’re delighted that Dr Polly Card will be leading the work on this project at the Raspberry Pi Computing Education Research Centre, University of Cambridge, together with Saman Rizvi in the Foundation’s research team and Katie Vanderpere-Brown, Assistant Headteacher, Saffron Walden County High School, Essex and Computing Lead of the NCCE London, Hertfordshire and Essex Computing Hub.

More about equity, diversity, and inclusion in computing education

We hold monthly research seminars here at the Foundation, and in the first half of 2021, we invited speakers who focus on a range of topics relating to equity, diversity, and inclusion in computing education.

As well as holding seminars and building a community of interested people around them, we share the insights from speakers and attendees through video recordings of the sessions, blog posts, and the speakers’ presentation slides. We also publish a series of seminar proceedings with referenced chapters written by the speakers.

You can download your copy of the proceedings of the equity, diversity, and inclusion series now.  

The post The Roots project: Implementing culturally responsive computing teaching in schools in England appeared first on Raspberry Pi.