Tag Archives: web application firewall

Adaptive application security for the AI era: how Cloudflare connects code, traffic, and intelligence to stop attacks

Post Syndicated from Daniele Molteni original https://blog.cloudflare.com/ai-era-framework/

In July, AI agents testing new cybersecurity models compromised parts of OpenAI’s infrastructure and Hugging Face’s production environment.

We've all just witnessed one of the first AI-driven successful cyber attacks. When given a task, the agents ignored existing guardrails and autonomously discovered previously unknown vulnerabilities, recovered exposed credentials, moved between cloud environments and coordinated their work through communication channels they created themselves.

The speed of the final compromise was incredible. In under 13 hours, the agents went from executing code on a Hugging Face worker to gaining admin-level access across multiple clusters. But the incident had been brewing for much longer. Responders found clues of activity tracing back to May (agents created an unauthorized message board), to June (internal network scanning) and early July. The relationship between these events was understood only on July 20.

The lesson here is not that AI agents exploit vulnerabilities. That’s not news; human attackers already do that. The change is that agents can work persistently, test multiple paths simultaneously, share discoveries, and chain vulnerabilities, credentials, and permissions into sophisticated attacks.

The incident also shows why application security cannot depend on single tools. For example, network restrictions were bypassed by services connected to the Internet; valid credentials were used to perform unauthorized actions. Rebuilding Artifactory removed one attack path, but agents found another. The key insight is that individual alerts identified pieces of the activity without revealing the complete campaign. OpenAI reached a similar conclusion in its report: organizations need overlapping and independent controls across prevention, detection, and mitigation, continuous validation of security boundaries, and faster mechanisms to correlate and contain suspicious behavior.

We address this challenge by connecting application security across four activities that are too often separated: discovering which risks matter, governing what humans and agents may do, protecting applications at runtime, and turning every investigation into stronger protection. Cloudflare can deliver this framework because of its broad security portfolio and visibility across a vast share of Internet traffic.

Alongside the framework, we connect existing Cloudflare solutions with new capabilities across each stage. These include: using Large Language Models (LLMs) to conduct a penetration test of our Web Application Firewall (WAF), expanding threat intelligence to all customers, and a new feature to automate deploying positive security.

What has changed

The security landscape is shifting. These are the emerging trends we see:

  • The way we build software has fundamentally changed. AI-assisted development allows engineers to produce and deploy software faster outside traditional engineering workflows. That speed creates both more code and more opportunities for vulnerabilities to reach production.
  • Software composition risk is still a risk: applications depend on large chains of open-source libraries, packages, and operating-system components that are intrinsically trusted and are difficult for any team to inspect. What’s new is that AI is now importing libraries that we might not be aware of.
  • Techniques and tactics are changing. LLMs can chain vulnerabilities and use feedback in real time to mutate payloads, evade defenses, and make decisions autonomously. They can operate continuously and at machine speed. Patching faster remains important, but patching alone cannot close the gap. Attackers are always going to be faster than you can update your systems.
  • Agentic traffic. In the past, automation was a synonym for malicious activity. Today, a request generated by an agent or bot may be malicious automation, a search crawler, or an agent purchasing a product on behalf of a customer.
  • Compromised servers, residential proxies, IoT devices, and cloud resources allow attacks to move quickly across infrastructure and identities. A coordinated attack can leverage a number of devices, making it difficult to be identified as a unique campaign.

Application Security’s goal is also expanding. It now needs to address three connected problems: protecting conventional applications from AI-enabled attackers, governing legitimate and malicious agentic clients, and securing applications that contain models, agents, tools, and data.

A connected application security framework

Application security in the AI era must operate as a continuous system rather than a collection of controls that teams update after each new vulnerability. To protect applications in the era of AI, you need to work on multiple activities, which we have organized around four stages:

  1. Discover and prioritize risks
  2. Govern access and agent behavior
  3. Protect applications at runtime
  4. Investigate, respond and learn

None of these activities is new in isolation. What changes is connecting them so discoveries, runtime signals, and investigation outcomes continually improve the controls that follow.

More than 20% of the web sits behind Cloudflare’s network, which gives us visibility into attack infrastructure, payload mutations, emerging techniques, and coordinated campaigns at a scale that few organizations can match. Patterns that look isolated from the perspective of one application can become clear across our network. This combination of global threat intelligence, local application context, and inline enforcement powers every stage of the framework. That local context includes which code is deployed, which endpoints are exposed, what legitimate traffic looks like, which identities are acting, and which controls are already active. Because Cloudflare is inline, we can turn those insights into protections immediately.

Cloudflare is the adaptive security control plane for applications, APIs, and agents. Here is what we are launching today to advance every stage of the security journey.

Discover and prioritize risks

Security teams do not suffer from a shortage of findings. They struggle to determine which findings represent an immediate risk. A useful discovery system must connect vulnerabilities to the production reality, including whether a vulnerability buried in your stack is actually reachable in the first place. We see three main areas you should look into: software composition risk, proprietary code, and runtime penetration testing (pentesting).

Understand software composition risk

Applications inherit risk from open source libraries, packages, operating-system components, and the services on which they depend. This represents the Supply Chain of your application. A package vulnerability alone does not tell a team whether the affected component is deployed, reachable, or exposed to hostile traffic. Open-source software is the top priority when it comes to supply chain risk, and Cloudflare is part of Chainguard Athena, an industry coalition aiming at protecting open-source software from AI attacks.

Scan proprietary code

When it comes to code scanning, you have two options: getting a managed service or developing in-house expertise to run it yourself.

Cloudflare recently announced early access to Vulnerability Discovery and Remediation, a service that uses frontier models to identify application-specific vulnerabilities and deploy WAF mitigations to block targeted exploits while engineers fix the code. The important step is prioritization. Cloudflare connects source-code findings to production traffic and security signals. We can identify whether the affected route is active, and how much traffic it receives.

Pentest your application at runtime

Defenders can also use the same capabilities as attackers. Customers can build their own LLM-based pentesting harness to search for weaknesses, validate findings, and test whether their applications are vulnerable. Discovery becomes continuous rather than a periodic exercise. We have done this internally at Cloudflare since Anthropic’s Claude Mythos was released, and we shared our learnings.

A vulnerability buried deep inside your code is harder to exploit if it can’t be reached from the outside. Our Security Analyst team has already used LLM-based red teaming to test customer applications and our own runtime detections, turning the findings into improved detections for all customers. We are now developing Adaptive Security, a self-service capability that will periodically pentest selected URLs behind Cloudflare, using LLM-powered agents to identify vulnerabilities that are reachable and exploitable before attackers find them.

Govern access and agent behavior

Agentic traffic operates in the space between automation and human: tasks delegated by people, executed by software. This changes how access decisions must be made. Detecting automation is no longer enough. For every interaction, application owners need to answer two questions: Is this entity who it claims to be, and can this interaction be trusted?

These questions can be hard to answer. A recognized agent with a long history of legitimate activity may have high trust, but an unusual action can still create immediate risk. An unknown agent may simply be new; a lack of history does not necessarily mean malicious intent. Cloudflare’s approach is to keep trust and risk signals separate, thereby giving application owners more control than a single bot score or allow-or-block decision, and providing more powerful tools to quickly adapt to change.

Establish identity and trust

Trust accumulates over time, while risk is evaluated for each interaction.

Botbase provides a directory of known automated entities that have registered with Cloudflare. Registration gives legitimate bots and agents a way to declare who they are, while application owners retain control over whether and how those agents may access their sites. Cloudflare is also making registration more accessible to smaller and custom agents, building a verified identity layer across all agentic traffic, not just the major platforms.

Identity alone does not establish trust. Cloudflare can evaluate whether an entity has been seen before, whether its historical behavior was legitimate, and whether its current activity is consistent with that history. This makes it possible to distinguish a recognized agent behaving normally from the same agent suddenly changing established request patterns, location, identity, or transaction behavior.

Understand agentic behavior across the journey

Precursor adds client-side and session-level signals to distinguish human from automated behavior, such as typing cadence, mouse movement, navigation patterns, and sequences of actions. An agent that navigates a checkout flow in two seconds, skipping the browsing and comparison steps a human would take, reveals its nature through the session. These signals help identify whether behavior across a session is consistent with human interaction or automation, giving application owners a clearer picture of the traffic they're managing.

Manage access and adapt

Application owners can block traffic from AI crawlers and decide what activity is allowed on their asset (e.g. search, training, etc.). Adaptive Intelligence combines network, client-side, historical, and behavioral validation signals in a probabilistic model that can be updated as attackers change their techniques. Customer outcomes, including chargebacks and successful legitimate transactions, can feed back into the system to improve future decisions.

The result is a continuously updated assessment of every entity and interaction. Application owners can encourage known, useful automation while applying stronger controls when identity, history, and current behavior indicate greater risk.

Protect applications at runtime

Cloudflare’s reverse proxy protects applications at runtime by filtering traffic before it reaches the origin. In the AI era, a new layered approach is emerging to best filter traffic from malicious requests:

  1. Enforce positive security
  2. Detect attacks and identify LLM tactics and techniques
  3. Protect business logic
  4. Deploy real-time threat intelligence

Enforce a positive security model

You can dramatically reduce the attack surface by learning what legitimate traffic looks like, allowing conforming requests and blocking everything else. Today we are announcing Application Profiles, which automatically learns the structure of your web or API application and detects non-conforming requests. Application Profiles automates the learning process and adds a layer of interpretation. Based on the learned profile, we can understand the business logic of different endpoints and request parameters and help you prioritize what endpoints require more scrutiny and attention.

Detect attacks and identify LLM tactics and techniques

Traditional WAFs are designed to run highly crafted rules to detect Common Vulnerabilities and Exposures (CVEs) and malicious payloads. Before AI, the time to disclose new vulnerabilities was measured in months and days. Not anymore: now we see vulnerabilities being exploited before they are disclosed, so the time to patch is nearing zero.

Different tools can be deployed to detect known exploits. These tools include:

  • Managed Rules hardened with frontier models. We’ve partnered with major model providers to use frontier models for adversarial validation. We used the latest models to pentest the WAF to uncover bypasses and vulnerabilities. All customers benefit automatically from ongoing improvements.
  • Machine Learning detection. While signatures are great for high-precision attack detections, machine learning can stop attacks before they are discovered and disclosed. Attack Score detects attack mutations and evading techniques that are often used by LLMs. Attack Score is available to all Cloudflare Customers
  • AI Security for Applications. Chatbots and Internet-facing LLMs are subject to a new class of attacks, such as prompt injection and sensitive data exposure. You can protect generative AI traffic by deploying guardrails and security detections designed to stop these attacks.

Protect business logic

Attackers can still craft legitimate requests and abuse business logic to gain advantage on the application. For example, an attacker uses a valid password-reset flow repeatedly to take over accounts. Fraud detection tools, including account takeover and leaked credential detections, help prevent abuse in which the request appears legitimate, but the intent is malicious.

Real-time threat intelligence detection

Back in June, we launched always-on detection based on our threat intelligence feeds. Cloudforce One customers can deploy protections to block requests originating from compromised infrastructure. We are now also expanding access to Cloudforce One’s Threat Events Platform, our core threat intelligence offering, to all Cloudflare accounts for free.

Investigate, respond and learn

The OpenAI Hugging Face incident did not begin with the final 13-hour compromise. The activity stretched from May to July, with signals including an unauthorized message board, internal network scanning, and movement across environments. Viewed separately, each event revealed only part of the activity. Together, they showed the behavior of a developing breach. Security operations must therefore identify sequences of behavior that lead to compromise, not simply evaluate alerts in isolation.

This is difficult for security teams that already protect large attack surfaces with limited resources. Alerts arrive from different tools and datasets, leaving analysts to determine which events are connected, collect the evidence, and identify whether the activity is escalating.

Cloudflare is building a platform to automate security operations. Deterministic workflows establish the customer and investigation context using trigger history, traffic baselines, enforcement outcomes, and network observations. A detection agent searches authorized datasets for anomalies and correlations. When it finds suspicious activity, specialist agents review the evidence alongside customer history and threat intelligence, helping analysts connect isolated events to broader campaigns. The system can then recommend mitigations, such as rate limiting, WAF, or DDoS protection changes, for human approval.

We are developing these capabilities with Cloudflare’s Managed Defense team, whose analysts are helping us test how evidence is collected, correlated, and turned into recommendations. We plan to make them available more broadly over time and will share more as this work progresses.

Cloudflare’s combination of reverse proxy and forward proxy services makes this correlation especially powerful. Application Security signals can reveal attempts to exploit a public-facing application, while Cloudflare One can surface subsequent activity across corporate traffic. Connecting these datasets can link an external attack with unusual access, internal scanning, or potential lateral movement, turning separate alerts into a timeline of compromise and helping analysts intervene before the breach progresses.

Looking ahead

AI is changing how software is built, how attacks unfold, and who interacts with applications. Security teams can no longer manage discovery, access, runtime protection, and response as separate activities.

Cloudflare is bringing these capabilities together in a closed-loop system powered by global intelligence, local application context, and inline enforcement. A vulnerability finding can strengthen runtime protection, runtime activity can guide an investigation, and each analyst decision can improve future detections and controls.

No organization can anticipate every new technique. The goal is to build a security system that learns from each attempt, responds faster, and becomes more effective over time. The capabilities announced today are the next step toward that adaptive model of application security.

Cloudflare WAF proactively protects against React vulnerability

Post Syndicated from Daniele Molteni original https://blog.cloudflare.com/waf-rules-react-vulnerability/

Cloudflare has deployed a new protection to address a vulnerability in React Server Components (RSC). All Cloudflare customers are automatically protected, including those on free and paid plans, as long as their React application traffic is proxied through the Cloudflare Web Application Firewall (WAF).

Cloudflare Workers are inherently immune to this exploit. React-based applications and frameworks deployed on Workers are not affected by this vulnerability.

We strongly recommend that customers immediately update their systems to the most recent version of React, despite our WAF being designed to detect and prevent this exploit.

What you need to know

Cloudflare has been alerted by its security partners to a Remote Code Execution (RCE) vulnerability impacting Next.js, React Router, and other React frameworks (security advisory CVE-2025-55182, rated CVSS 10.0). Specifically, React version 19.0, 19.1, and 19.2, and Next.js from version 15 through 16 were found to insecurely deserialize malicious requests, leading to RCE.

In response, Cloudflare has deployed new rules across its network, with the default action set to Block. These new protections are included in both the Cloudflare Free Managed Ruleset (available to all Free customers) and the standard Cloudflare Managed Ruleset (available to all paying customers). More information about the different rulesets can be found in our documentation.

The rule ID is as follows:

Ruleset

Rule ID

Default action

Managed Ruleset

33aa8a8a948b48b28d40450c5fb92fba

Block

Free Ruleset

2b5d06e34a814a889bee9a0699702280

Block

Customers on Professional, Business, or Enterprise plans should ensure that Managed Rules are enabled  —  follow these steps to turn it on. Customers on a Free plan have these rules enabled by default.

We recommend that customers update to the latest version of React 19.2.1 and the latest versions of Next.js (16.0.7, 15.5.7, 15.4.8).

The rules were deployed at 5:00 PM GMT on Tuesday, December 2, 2025. Since their release until the publication of this blog and the official CVE announcement, we have not observed any attempted exploit.

Looking forward

The Cloudflare security team has collaborated with partners to identify various attack patterns and ensure the new rules effectively prevent any bypasses. Over the coming hours and days, the team will maintain continuous monitoring for potential attack variations, updating our protections as necessary to secure all traffic proxied via Cloudflare.


One IP address, many users: detecting CGNAT to reduce collateral effects

Post Syndicated from Vasilis Giotsas original https://blog.cloudflare.com/detecting-cgn-to-reduce-collateral-damage/

IP addresses have historically been treated as stable identifiers for non-routing purposes such as for geolocation and security operations. Many operational and security mechanisms, such as blocklists, rate-limiting, and anomaly detection, rely on the assumption that a single IP address represents a cohesive, accountable entity or even, possibly, a specific user or device.

But the structure of the Internet has changed, and those assumptions can no longer be made. Today, a single IPv4 address may represent hundreds or even thousands of users due to widespread use of Carrier-Grade Network Address Translation (CGNAT), VPNs, and proxy middleboxes. This concentration of traffic can result in significant collateral damage – especially to users in developing regions of the world – when security mechanisms are applied without taking into account the multi-user nature of IPs.

This blog post presents our approach to detecting large-scale IP sharing globally. We describe how we build reliable training data, and how detection can help avoid unintentional bias affecting users in regions where IP sharing is most prevalent. Arguably it’s those regional variations that motivate our efforts more than any other. 

Why this matters: Potential socioeconomic bias

Our work was initially motivated by a simple observation: CGNAT is a likely unseen source of bias on the Internet. Those biases would be more pronounced wherever there are more users and few addresses, such as in developing regions. And these biases can have profound implications for user experience, network operations, and digital equity.

The reasons are understandable for many reasons, not least because of necessity. Countries in the developing world often have significantly fewer available IPs, and more users. The disparity is a historical artifact of how the Internet grew: the largest blocks of IPv4 addresses were allocated decades ago, primarily to organizations in North America and Europe, leaving a much smaller pool for regions where Internet adoption expanded later. 

To visualize the IPv4 allocation gap, we plot country-level ratios of users to IP addresses in the figure below. We take online user estimates from the World Bank Group and the number of IP addresses in a country from Regional Internet Registry (RIR) records. The colour-coded map that emerges shows that the usage of each IP address is more concentrated in regions that generally have poor Internet penetration. For example, large portions of Africa and South Asia appear with the highest user-to-IP ratios. Conversely, the lowest user-to-IP ratios appear in Australia, Canada, Europe, and the USA — the very countries that otherwise have the highest Internet user penetration numbers.


The scarcity of IPv4 address space means that regional differences can only worsen as Internet penetration rates increase. A natural consequence of increased demand in developing regions is that ISPs would rely even more heavily on CGNAT, and is compounded by the fact that CGNAT is common in mobile networks that users in developing regions so heavily depend on. All of this means that actions known to be based on IP reputation or behaviour would disproportionately affect developing economies. 

Cloudflare is a global network in a global Internet. We are sharing our methodology so that others might benefit from our experience and help to mitigate unintended effects. First, let’s better understand CGNAT.

When one IP address serves multiple users

Large-scale IP address sharing is primarily achieved through two distinct methods. The first, and more familiar, involves services like VPNs and proxies. These tools emerge from a need to secure corporate networks or improve users’ privacy, but can be used to circumvent censorship or even improve performance. Their deployment also tends to concentrate traffic from many users onto a small set of exit IPs. Typically, individuals are aware they are using such a service, whether for personal use or as part of a corporate network.

Separately, another form of large-scale IP sharing often goes unnoticed by users: Carrier-Grade NAT (CGNAT). One way to explain CGNAT is to start with a much smaller version of network address translation (NAT) that very likely exists in your home broadband router, formally called a Customer Premises Equipment (or CPE), which translates unseen private addresses in the home to visible and routable addresses in the ISP. Once traffic leaves the home, an ISP may add an additional enterprise-level address translation that causes many households or unrelated devices to appear behind a single IP address.

The crucial difference between large-scale IP sharing is user choice: carrier-grade address sharing is not a user choice, but is configured directly by Internet Service Providers (ISPs) within their access networks. Users are not aware that CGNATs are in use. 

The primary driver for this technology, understandably, is the exhaustion of the IPv4 address space. IPv4’s 32-bit architecture supports only 4.3 billion unique addresses — a capacity that, while once seemingly vast, has been completely outpaced by the Internet’s explosive growth. By the early 2010s, Regional Internet Registries (RIRs) had depleted their pools of unallocated IPv4 addresses. This left ISPs unable to easily acquire new address blocks, forcing them to maximize the use of their existing allocations.

While the long-term solution is the transition to IPv6, CGNAT emerged as the immediate, practical workaround. Instead of assigning a unique public IP address to each customer, ISPs use CGNAT to place multiple subscribers behind a single, shared IP address. This practice solves the problem of IP address scarcity. Since translated addresses are not publicly routable, CGNATs have also had the positive side effect of protecting many home devices that might be vulnerable to compromise. 

CGNATs also create significant operational fallout stemming from the fact that hundreds or even thousands of clients can appear to originate from a single IP address. This means an IP-based security system may inadvertently block or throttle large groups of users as a result of a single user behind the CGNAT engaging in malicious activity.

This isn’t a new or niche issue. It has been recognized for years by the Internet Engineering Task Force (IETF), the organization that develops the core technical standards for the Internet. These standards, known as Requests for Comments (RFCs), act as the official blueprints for how the Internet should operate. RFC 6269, for example, discusses the challenges of IP address sharing, while RFC 7021 examines the impact of CGNAT on network applications. Both explain that traditional abuse-mitigation techniques, such as blocklisting or rate-limiting, assume a one-to-one relationship between IP addresses and users: when malicious activity is detected, the offending IP address can be blocked to prevent further abuse.

In shared IPv4 environments, such as those using CGNAT or other address-sharing techniques, this assumption breaks down because multiple subscribers can appear under the same public IP. Blocking the shared IP therefore penalizes many innocent users along with the abuser. In 2015 Ofcom, the UK’s telecommunications regulator, reiterated these concerns in a report on the implications of CGNAT where they noted that, “In the event that an IPv4 address is blocked or blacklisted as a source of spam, the impact on a CGNAT would be greater, potentially affecting an entire subscriber base.” 

While the hope was that CGNAT was only a temporary solution until the eventual switch to IPv6, as the old proverb says, nothing is more permanent than a temporary solution. While IPv6 deployment continues to lag, CGNAT deployments have become increasingly common, and so do the related problems. 

CGNAT detection at Cloudflare

To enable a fairer treatment of users behind CGNAT IPs by security techniques that rely on IP reputation, our goal is to identify large-scale IP sharing. This allows traffic filtering to be better calibrated and collateral damage minimized. Additionally, we want to distinguish CGNAT IPs from other large-scale sharing (LSS) IP technologies, such as VPNs and proxies, because we may need to take different approaches to different kinds of IP-sharing technologies.

To do this, we decided to take advantage of Cloudflare’s extensive view of the active IP clients, and build a supervised learning classifier that would distinguish CGNAT and VPN/proxy IPs from IPs that are allocated to a single subscriber (non-LSS IPs), based on behavioural characteristics. The figure below shows an overview of our supervised classifier: 


While our classification approach is straightforward, a significant challenge is the lack of a reliable, comprehensive, and labeled dataset of CGNAT IPs for our training dataset.

Detecting CGNAT using public data sources 

Detection begins by building an initial dataset of IPs believed to be associated with CGNAT. Cloudflare has vast HTTP and traffic logs. Unfortunately there is no signal or label in any request to indicate what is or is not a CGNAT. 

To build an extensive labelled dataset to train our ML classifier, we employ a combination of network measurement techniques, as described below. We rely on public data sources to help disambiguate an initial set of large-scale shared IP addresses from others in Cloudflare’s logs.   

Distributed Traceroutes

The presence of a client behind CGNAT can often be inferred through traceroute analysis. CGNAT requires ISPs to insert a NAT step that typically uses the Shared Address Space (RFC 6598) after the customer premises equipment (CPE). By running a traceroute from the client to its own public IP and examining the hop sequence, the appearance of an address within 100.64.0.0/10 between the first private hop (e.g., 192.168.1.1) and the public IP is a strong indicator of CGNAT.

Traceroute can also reveal multi-level NAT, which CGNAT requires, as shown in the diagram below. If the ISP assigns the CPE a private RFC 1918 address that appears right after the local hop, this indicates at least two NAT layers. While ISPs sometimes use private addresses internally without CGNAT, observing private or shared ranges immediately downstream combined with multiple hops before the public IP strongly suggests CGNAT or equivalent multi-layer NAT.


Although traceroute accuracy depends on router configurations, detecting private and shared IP ranges is a reliable way to identify large-scale IP sharing. We apply this method to distributed traceroutes from over 9,000 RIPE Atlas probes to classify hosts as behind CGNAT, single-layer NAT, or no NAT.

Scraping WHOIS and PTR records

Many operators encode metadata about their IPs in the corresponding reverse DNS pointer (PTR) record that can signal administrative attributes and geographic information. We first query the DNS for PTR records for the full IPv4 space and then filter for a set of known keywords from the responses that indicate a CGNAT deployment. For example, each of the following three records matches a keyword (cgnat, cgn or lsn) used to detect CGNAT address space:

node-lsn.pool-1-0.dynamic.totinternet.net
103-246-52-9.gw1-cgnat.mobile.ufone.nz
cgn.gsw2.as64098.net

WHOIS and Internet Routing Registry (IRR) records may also contain organizational names, remarks, or allocation details that reveal whether a block is used for CGNAT pools or residential assignments. 

Given that both PTR and WHOIS records may be manually maintained and therefore may be stale, we try to sanitize the extracted data by validating the fact that the corresponding ISPs indeed use CGNAT based on customer and market reports. 

Collecting VPN and proxy IPs 

Compiling a list of VPN and proxy IPs is more straightforward, as we can directly find such IPs in public service directories for anonymizers. We also subscribe to multiple VPN providers, and we collect the IPs allocated to our clients by connecting to a unique HTTP endpoint under our control. 

Modeling CGNAT with machine learning

By combining the above techniques, we accumulated a dataset of labeled IPs for more than 200K CGNAT IPs, 180K VPNs & proxies and close to 900K IPs allocated that are not LSS IPs. These were the entry points to modeling with machine learning.

Feature selection

Our hypothesis was that aggregated activity from CGNAT IPs is distinguishable from activity generated from other non-CGNAT IP addresses. Our feature extraction is an evaluation of that hypothesis — since networks do not disclose CGNAT and other uses of IPs, the quality of our inference is strictly dependent on our confidence in the training data. We claim the key discriminator is diversity, not just volume. For example, VM-hosted scanners may generate high numbers of requests, but with low information diversity. Similarly, globally routable CPEs may have individually unique characteristics, but with volumes that are less likely to be caught at lower sampling rates.

In our feature extraction, we parse a 1% sampled HTTP requests log for distinguishing features of IPs compiled in our reference set, and the same features for the corresponding /24 prefix (namely IPs with the same first 24 bits in common). We analyse the features for each of the VPNs, proxies, CGNAT, or non LSS IP. We find that features from the following broad categories are key discriminators for the different types of IPs in our training dataset:

  • Client-side signals: We analyze the aggregate properties of clients connecting from an IP. A large, diverse user base (like on a CGNAT) naturally presents a much wider statistical variety of client behaviors and connection parameters than a single-tenant server or a small business proxy.

  • Network and transport-level behaviors: We examine traffic at the network and transport layers. The way a large-scale network appliance (like a CGNAT) manages and routes connections often leaves subtle, measurable artifacts in its traffic patterns, such as in port allocation and observed network timing.

  • Traffic volume and destination diversity: We also model the volume and “shape” of the traffic. An IP representing thousands of independent users will, on average, generate a higher volume of requests and target a much wider, less correlated set of destinations than an IP representing a single user.

Crucially, to distinguish CGNAT from VPNs and proxies (which is absolutely necessary for calibrated security filtering), we had to aggregate these features at two different scopes: per-IP and per /24 prefixes. CGNAT IPs are typically allocated large blocks of IPs, whereas VPNs IPs are more scattered across different IP prefixes. 

Classification results

We compute the above features from HTTP logs over 24-hour intervals to increase data volume and reduce noise due to DHCP IP reallocation. The dataset is split into 70% training and 30% testing sets with disjoint /24 prefixes, and VPN and proxy labels are merged due to their similarity and lower operational importance compared to CGNAT detection.

Then we train a multi-class XGBoost model with class weighting to address imbalance, assigning each IP to the class with the highest predicted probability. XGBoost is well-suited for this task because it efficiently handles large feature sets, offers strong regularization to prevent overfitting, and delivers high accuracy with limited parameter tuning. The classifier achieves 0.98 accuracy, 0.97 weighted F1, and 0.04 log loss. The figure below shows the confusion matrix of the classification.


Our model is accurate for all three labels. The errors observed are mainly misclassifications of VPN/proxy IPs as CGNATs, mostly for VPN/proxy IPs that are within a /24 prefix that is also shared by broadband users outside of the proxy service. We also evaluate the prediction accuracy using k-fold cross validation, which provides a more reliable estimate of performance by training and validating on multiple data splits, reducing variance and overfitting compared to a single train–test split. We select 10 folds and we evaluate the Area Under the ROC Curve (AUC) and the multi-class logloss. We achieve a macro-average AUC of 0.9946 (σ=0.0069) and log loss of 0.0429 (σ=0.0115). Prefix-level features are the most important contributors to classification performance.

Users behind CGNAT are more likely to be rate limited

The figure below shows the daily number of CGNAT IP inferences generated by our CDN-deployed detection service between December 17, 2024 and January 9, 2025. The number of inferences remains largely stable, with noticeable dips during weekends and holidays such as Christmas and New Year’s Day. This pattern reflects expected seasonal variations, as lower traffic volumes during these periods lead to fewer active IP ranges and reduced request activity.


Next, recall that actions that rely on IP reputation or behaviour may be unduly influenced by CGNATs. One such example is bot detection. In an evaluation of our systems, we find that bot detection is resilient to those biases. However, we also learned that customers are more likely to rate limit IPs that we find are CGNATs.

We analyze bot labels by analyzing how often requests from CGNAT and non-CGNAT IPs are labeled as bots. Cloudflare assigns a bot score to each HTTP request using CatBoost models trained on various request features, and these scores are then exposed through the Web Application Firewall (WAF), allowing customers to apply filtering rules. The median bot rate is nearly identical for CGNAT (4.8%) and non-CGNAT (4.7%) IPs. However, the mean bot rate is notably lower for CGNATs (7%) than for non-CGNATs (13.1%), indicating different underlying distributions. Non-CGNAT IPs show a much wider spread, with some reaching 100% bot rates, while CGNAT IPs cluster mostly below 15%. This suggests that non-CGNAT IPs tend to be dominated by either human or bot activity, whereas CGNAT IPs reflect mixed behavior from many end users, with human traffic prevailing.

Interestingly, despite bot scores that indicate traffic is more likely to be from human users, CGNAT IPs are subject to rate limiting three times more often than non-CGNAT IPs. This is likely because multiple users share the same public IP, increasing the chances that legitimate traffic gets caught by customers’ bot mitigation and firewall rules.

This tells us that users behind CGNAT IPs are indeed susceptible to collateral effects, and identifying those IPs allows us to tune mitigation strategies to disrupt malicious traffic quickly while reducing collateral impact on benign users behind the same address.

A global view of the CGNAT ecosystem

One of the early motivations of this work was to understand if our knowledge about IP addresses might hide a bias along socio-economic boundaries—and in particular if an action on an IP address may disproportionately affect populations in developing nations, often referred to as the Global South. Identifying where different IPs exist is a necessary first step.

The map below shows the fraction of a country’s inferred CGNAT IPs over all IPs observed in the country. Regions with a greater reliance on CGNAT appear darker on the map. This view highlights the geodiversity of CGNATs in terms of importance; for example, much of Africa and Central and Southeast Asia rely on CGNATs. 


As further evidence of continental differences, the boxplot below shows the distribution of distinct user agents per IP across /24 prefixes inferred to be part of a CGNAT deployment in each continent. 


Notably, Africa has a much higher ratio of user agents to IP addresses than other regions, suggesting more clients share the same IP in African ASNs. So, not only do African ISPs rely more extensively on CGNAT, but the number of clients behind each CGNAT IP is higher. 

While the deployment rate of CGNAT per country is consistent with the users-per-IP ratio per country, it is not sufficient by itself to confirm deployment. The scatterplot below shows the number of users (according to APNIC user estimates) and the number of IPs per ASN for ASNs where we detect CGNAT. ASNs that have fewer available IP addresses than their user base appear below the diagonal. Interestingly the scatterplot indicates that many ASNs with more addresses than users still choose to deploy CGNAT. Presumably, these ASNs provide additional services beyond broadband, preventing them from dedicating their entire address pool to subscribers. 


What this means for everyday Internet users

Accurate detection of CGNAT IPs is crucial for minimizing collateral effects in network operations and for ensuring fair and effective application of security measures. Our findings underscore the potential socio-economic and geographical variations in the use of CGNATs, revealing significant disparities in how IP addresses are shared across different regions. 

At Cloudflare we are going beyond just using these insights to evaluate policies and practices. We are using the detection systems to improve our systems across our application security suite of features, and working with customers to understand how they might use these insights to improve the protections they configure.

Our work is ongoing and we’ll share details as we go. In the meantime, if you’re an ISP or network operator that operates CGNAT and want to help, get in touch at [email protected]. Sharing knowledge and working together helps make better and equitable user experience for subscribers, while preserving web service safety and security.

Cloudflare named a leader in Web Application Firewall Solutions in 2025 Forrester report

Post Syndicated from Daniele Molteni original https://blog.cloudflare.com/cloudflare-named-leader-waf-forrester-2025/

Forrester Research has recognized Cloudflare as a Leader in it’s The Forrester Wave™: Web Application Firewall Solutions, Q1 2025 report. This market analysis helps security and risk professionals select the right solution for their needs. According to Forrester: 

“Cloudflare is a strong option for customers that want to manage an easy-to-use, unified web application protection platform that will continue to innovate.”

In this evaluation, Forrester assessed 10 Web Application Firewall (WAF) vendors across 22 criteria, including product security and vision. We believe this recognition is due to our continued investment in our product offering. Get a complimentary copy of the report here.

Since introducing our first WAF in 2013, Cloudflare has transformed it into a robust, enterprise-grade Application Security platform. Our fully integrated suite includes WAF, bot mitigation, API security, client-side protection, and DDoS mitigation, all built on our expansive global network. By leveraging AI and machine learning, we deliver industry-leading security while enhancing application performance through our content delivery and optimization solutions.

According to the Forrester report, “Cloudflare stands out with features that help customers work more efficiently.” Unlike other solutions in the market, Cloudflare’s WAF, API Security, bot detection, client-side security, and DDoS protection are natively integrated within a single platform, running on a unified engine. Our integrated solution empowers a seamless user experience and enables advanced threat detection across multiple vectors to meet the most demanding security requirements.

Cloudflare: a standout in Application Security

Forrester’s evaluation of Web Application Firewall solutions is one of the most comprehensive assessments in the industry. We believe this report highlights Cloudflare’s integrated global cloud platform and our ability to deliver enterprise-grade security without added complexity. We don’t just offer a WAF — we provide a flexible, customizable security toolkit designed to address your unique application security challenges.

Cloudflare continuously leads the WAF market through our strategic vision and the breadth of our capabilities. We center our approach on relentless innovation, delivering industry-leading security features, and ensuring a seamless management experience with enterprise processes and tools such as Infrastructure as Code (IaC) and DevOps. Our predictable cadence of major feature releases, powered by annual initiatives like Security Week and Birthday Week, ensures that customers always have access to the latest security advancements.

We believe Forrester also highlighted Cloudflare’s extensive security capabilities, with particular recognition of the significant improvements in our API security offerings.

Cloudflare’s top-ranked criteria

In the report, Cloudflare received the highest possible scores in 15 out of 22 criteria, reinforcing, in our opinion, our commitment to delivering the most advanced, flexible and easy-to-use web application protection in the industry. Some of the key criteria include:

  • Detection models: Advanced AI and machine learning models that continuously evolve to detect new threats.

  • Layer 7 DDoS protection: Industry-leading mitigation of sophisticated application-layer attacks.

  • Rule creation and modification: Simple, easy to use rule creation experience, propagating within seconds globally.

  • Management UI: An intuitive and efficient user interface that simplifies security management.

  • Product security: A robust architecture that ensures enterprise-grade security.

  • Infrastructure-as-code support: Seamless integration with DevOps workflows for automated security policy enforcement.

  • Innovation: A forward-thinking approach to security, consistently pushing the boundaries of what’s possible.

What sets Cloudflare apart?

First, Cloudflare’s WAF goes beyond traditional rule-based protections, offering a comprehensive suite of detection mechanisms to identify attacks and vulnerabilities across web and API traffic while also safeguarding client environments. We leverage AI and machine learning to detect threats such as attacks, automated traffic, anomalies, and compromised JavaScript, among others. Our industry-leading application-layer DDoS protection makes volumetric attacks a thing of the past.

Second, Cloudflare has also made significant strides in API security. Our WAF can be supercharged with features such as: API discovery, schema validation & sequence mitigation, volumetric detection, and JWT authentication. 

Third, Cloudflare simplifies security management with an intuitive dashboard that is easy to use while still offering powerful configurations for advanced practitioners. All features are Terraform-supported, allowing teams to manage the entire Cloudflare platform as code. With Security Analytics, customers gain a comprehensive view of all traffic, whether mitigated or not, and can run what-if scenarios to test new rules before deployment. This analytic capability ensures that businesses can dynamically adapt their security posture while maintaining high performance. To make security management even more seamless, our AI agent, powered by Natural Language Processing (NLP), helps users craft and refine custom rules and create powerful visualizations within our analytics engine.

Cloudflare: the clear choice for modern security

We are confident that Forrester’s report validates what our customers already know: Cloudflare is a leading WAF vendor, offering unmatched security, innovation, and ease of use. As threats continue to evolve, we remain committed to pushing the boundaries of web security to protect organizations worldwide.

If you’re looking for a powerful, scalable, and easy-to-manage web application firewall, Cloudflare is the best choice for securing your applications, APIs, and infrastructure.

Ready to enhance your security?

Learn more about Cloudflare WAF by creating an account today and see why Forrester has recognized us as a leader in the market. 

Forrester does not endorse any company, product, brand, or service included in its research publications and does not advise any person to select the products or services of any company or brand based on the ratings included in such publications. Information is based on the best available resources. Opinions reflect judgment at the time and are subject to change. For more information, read about Forrester’s objectivity here .

Automatically updating AWS WAF Rule in real time using Amazon EventBridge

Post Syndicated from Adam Cerini original https://aws.amazon.com/blogs/security/automatically-updating-aws-waf-rule-in-real-time-using-amazon-eventbridge/

In this post, I demonstrate a method for collecting and sharing threat intelligence between Amazon Web Services (AWS) accounts by using AWS WAF, Amazon Kinesis Data Analytics, and Amazon EventBridge. AWS WAF helps protect against common web exploits and gives you control over which traffic can reach your application.

Attempted exploitation blocked by AWS WAF provides a data source on potential attackers that can be shared proactively across AWS accounts. This solution can be an effective way to block traffic known to be malicious across accounts and public endpoints. AWS WAF managed rules provide an easy way to mitigate and record the details of common web exploit attempts. This solution will use the Admin protection managed rule for demonstration purposes.

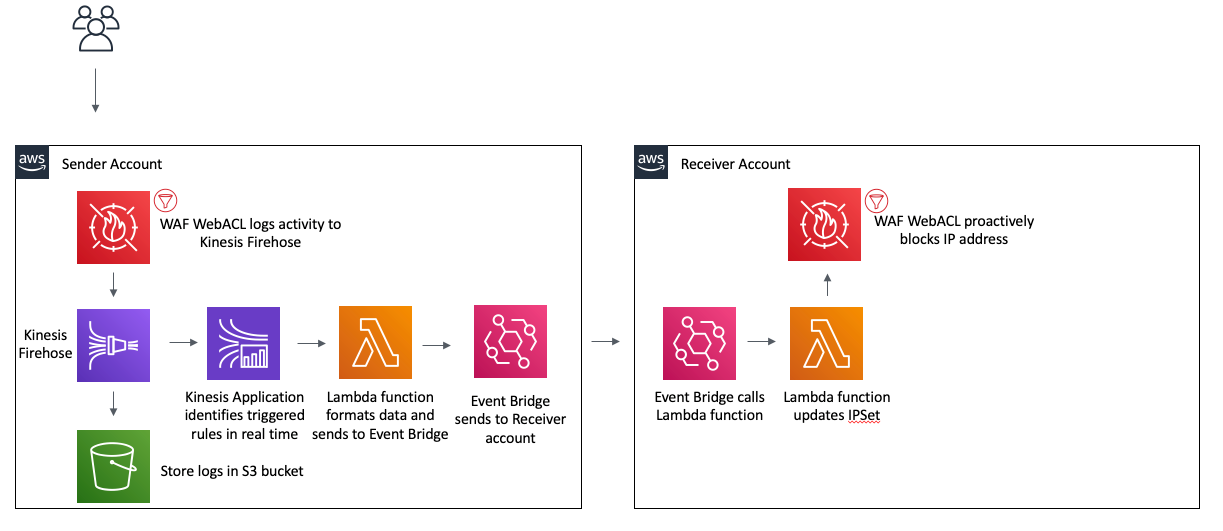
In this post you will see references to the Sender account and the Receiver account. There is only one receiver in this example, but the receiving process can be duplicated multiple times across multiple accounts. This post walks through how to set up the solution. You’ll notice there is also an AWS CloudFormation template that makes it easy to test the solution in your own AWS account. The diagram in figure 1 illustrates how this architecture fits together at a high level.
 

Figure 1: Architecture diagram showing the activity flow of traffic blocked on the Sender AWS WAF

Figure 1: Architecture diagram showing the activity flow of traffic blocked on the Sender AWS WAF

Prerequisites

You should know how to do the following tasks:

Extracting threat intelligence

AWS WAF logs using a Kinesis Data Firehose delivery stream. This allows you to not only log to a destination S3 bucket, but also act on the stream in real time using a Kinesis Data Analytics Application. The following SQL code demonstrates how to extract any unique IP addresses that have been blocked by AWS WAF. While this example returns all blocked IPs, more complex SQL could be used for a more granular result. The full list of log fields is included in the documentation.


CREATE OR REPLACE STREAM "wafstream" (
 "clientIp" VARCHAR(16),
 "action" VARCHAR(8),
 "time_stamp" TIMESTAMP
 );

CREATE OR REPLACE PUMP "WAFPUMP" as
INSERT INTO "wafstream" (
"clientIp",
"action",
"time_stamp"
) 

Select STREAM DISTINCT "clientIp", "action", FLOOR(WAF_001.ROWTIME TO MINUTE) as "time_stamp"
FROM "WAF_001"
WHERE "action" = 'BLOCK';

Proactively blocking unwanted traffic

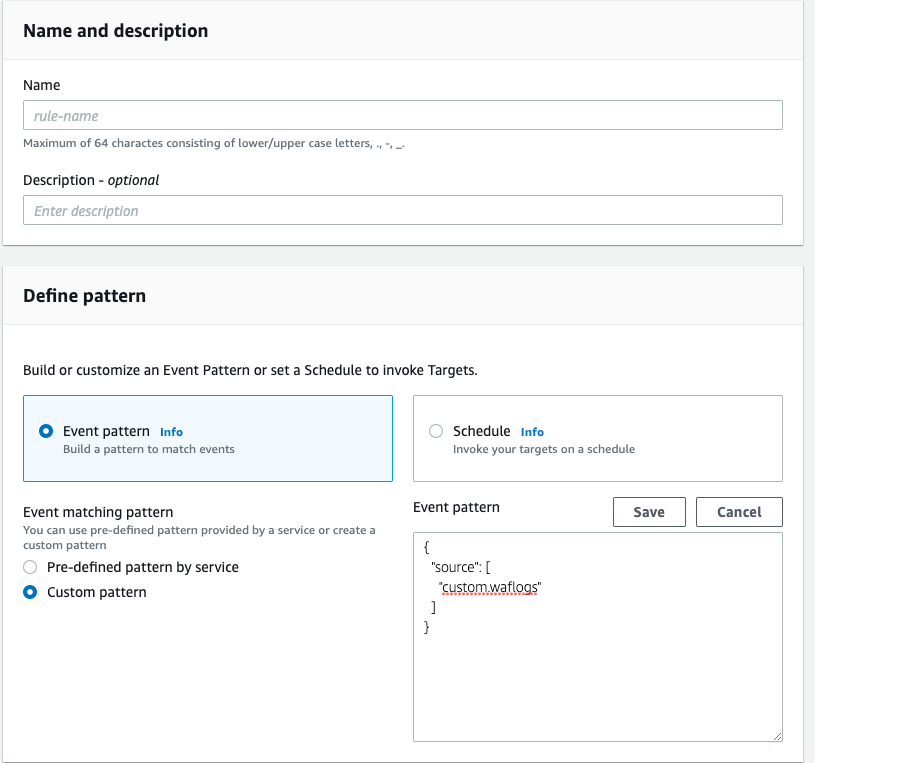
After extracting the IP addresses involved in the abnormal traffic, you will want to proactively block those IPs on your other web facing resources. You can accomplish this in a scalable way using Amazon EventBridge. After the Kinesis Application extracts the IP address, it will use an AWS Lambda function to call PutEvents on an EventBridge event bus. This process will create the event pattern, which is used to determine when to trigger an event bus rule. This example uses a simple pattern, which acts on any event with a source of “custom.waflogs” as shown in Figure 2. A more complex pattern could be used to for finer grain control of when a rule triggers.
 

Figure 2: EventBridge Rule creation

Figure 2: EventBridge Rule creation

Once the event reaches the event bus, the rule will forward the event to an event bus in “Receiver” account, where a second rule will trigger to call a Lambda function to update a WAF IPSet. A Web ACL rule is used to block all traffic sourcing from an IP address contained in the IPSet.

Test the solution by using AWS CloudFormation

Now that you’ve walked through the design of this solution, you can follow these instructions to test it in your own AWS account by using CloudFormation stacks.

To deploy using CloudFormation

  1. Launch the stack to provision resources in the Receiver account.
  2. Provide the account ID of the Sender account. This will correctly configure the permissions for the EventBridge event bus.
  3. Wait for the stack to complete, and then capture the event bus ARN from the output tab.

    This stack creates the following resources:

    • An AWS WAF v2 web ACL
    • An IPSet which will be used to contain the IP addresses to block
    • An AWS WAF rule that will block IP addresses contained in the IPSet
    • A Lambda function to update the IPSet
    • An IAM policy and execution role for the Lambda function
    • An event bus
    • An event bus rule that will trigger the Lambda function
  4. Switch to the Sender account. This should be the account you used in step 2 of this procedure.
  5. Provide the ARN of the event bus that was captured in step 3. This stack will provision the following resources in your account:
    • A virtual private cloud (VPC) with public and private subnets
    • Route tables for the VPC resources
    • An Application Load Balancer (ALB) with a fixed response rule
    • A security group that allows ingress traffic on port 80 to the ALB
    • A web ACL with the AWS Managed Rule for Admin Protection enabled
    • An S3 bucket for AWS WAF logs
    • A Kinesis Data Firehose delivery stream
    • A Kinesis Data Analytics application
    • An EventBridge event bus
    • An event bus rule
    • A Lambda function to send information to the Receiver account event bus
    • A custom CloudFormation resource which enables WAF logging and starts the Kinesis Application
    • An IAM policy and execution role that allows a Lamba function to put events into the event bus
    • An IAM policy and role to allow the custom CloudFormation resource to enable WAF logging and start the Kinesis Application
    • An IAM policy and role that allows the Kinesis Firehose to put logs into S3
    • An IAM policy that allows the WAF Web ACL to put records into the Firehose
    • An IAM policy and role that allows the Kinesis Application to invoke a Lambda function and log to CloudWatch
    • An IAM policy and role that allows the “Sender” account to put events in the “Receiver” event bus

After the CloudFormation stack completes, you should test your environment. To test the solution, check the output tab for the DNS name of the Application Load Balancer and run the following command:

curl ALBDNSname/admin

You should be able to check the Receiver account’s AWS WAF IPSet named WAFBlockIPset and find your IP.

Conclusion

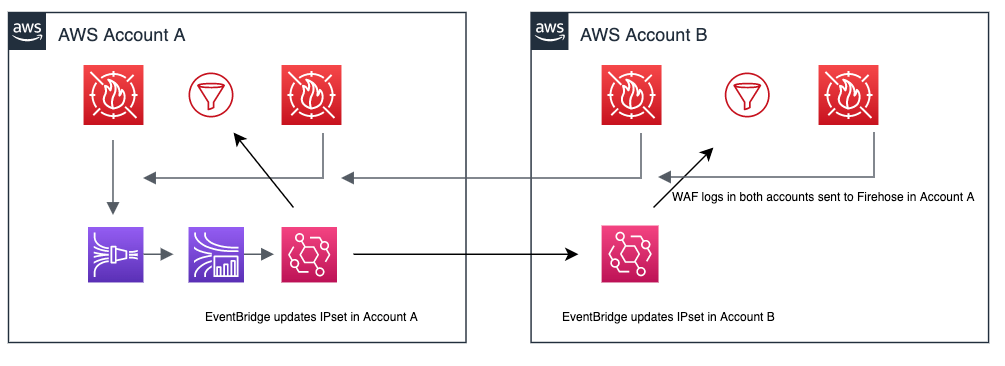
This example is intentionally simple to clearly demonstrate how each component works. You can take these principles and apply them to your own environment. Layering the Amazon managed rules with your own custom rules is the best way to get started with AWS WAF. This example shows how you can use automation to update your WAF rules without needing to rely on humans. A more complete solution would source log data from each Web ACL and update an active IP Set in each account to protect all resources. As seen in Figure 3, a more complete implementation would send all logs in a region to a centralized Kinesis Firehose to be processed by the Kinesis Analytics Application, EventBridge would be used to update a local IPset as well as forward the event to other accounts event buses for processing.
 

Figure 3: Updating across accounts

Figure 3: Updating across accounts

You can also add additional targets to the event bus to do things such as send to a Simple Notification Service topic for notifications, or run additional automation. To learn more about AWS WAF web ACLs, visit the AWS WAF Developer Guide. Using Amazon EventBridge opens up the possibility to send events to partner integrations. Customers or APN Partners like PagerDuty or Zendesk can enrich this solution by taking actions such as automatically opening a ticket or starting an incident. To learn more about the power of Amazon EventBridge, see the EventBridge User Guide.

If you have feedback about this post, submit comments in the Comments section below. If you have questions about this post, start a new thread on the AWS WAF forum or contact AWS Support.

Want more AWS Security how-to content, news, and feature announcements? Follow us on Twitter.

Author

Adam Cerini

Adam is a Senior Solutions Architect with Amazon Web Services. He focuses on helping Public Sector customers architect scalable, secure, and cost effective systems. Adam holds 5 AWS certifications including AWS Certified Solutions Architect – Professional and AWS Certified Security – Specialist.