All posts by Tanner Ryan

500 Tbps of capacity: 16 years of scaling our global network

Post Syndicated from Tanner Ryan original https://blog.cloudflare.com/500-tbps-of-capacity/

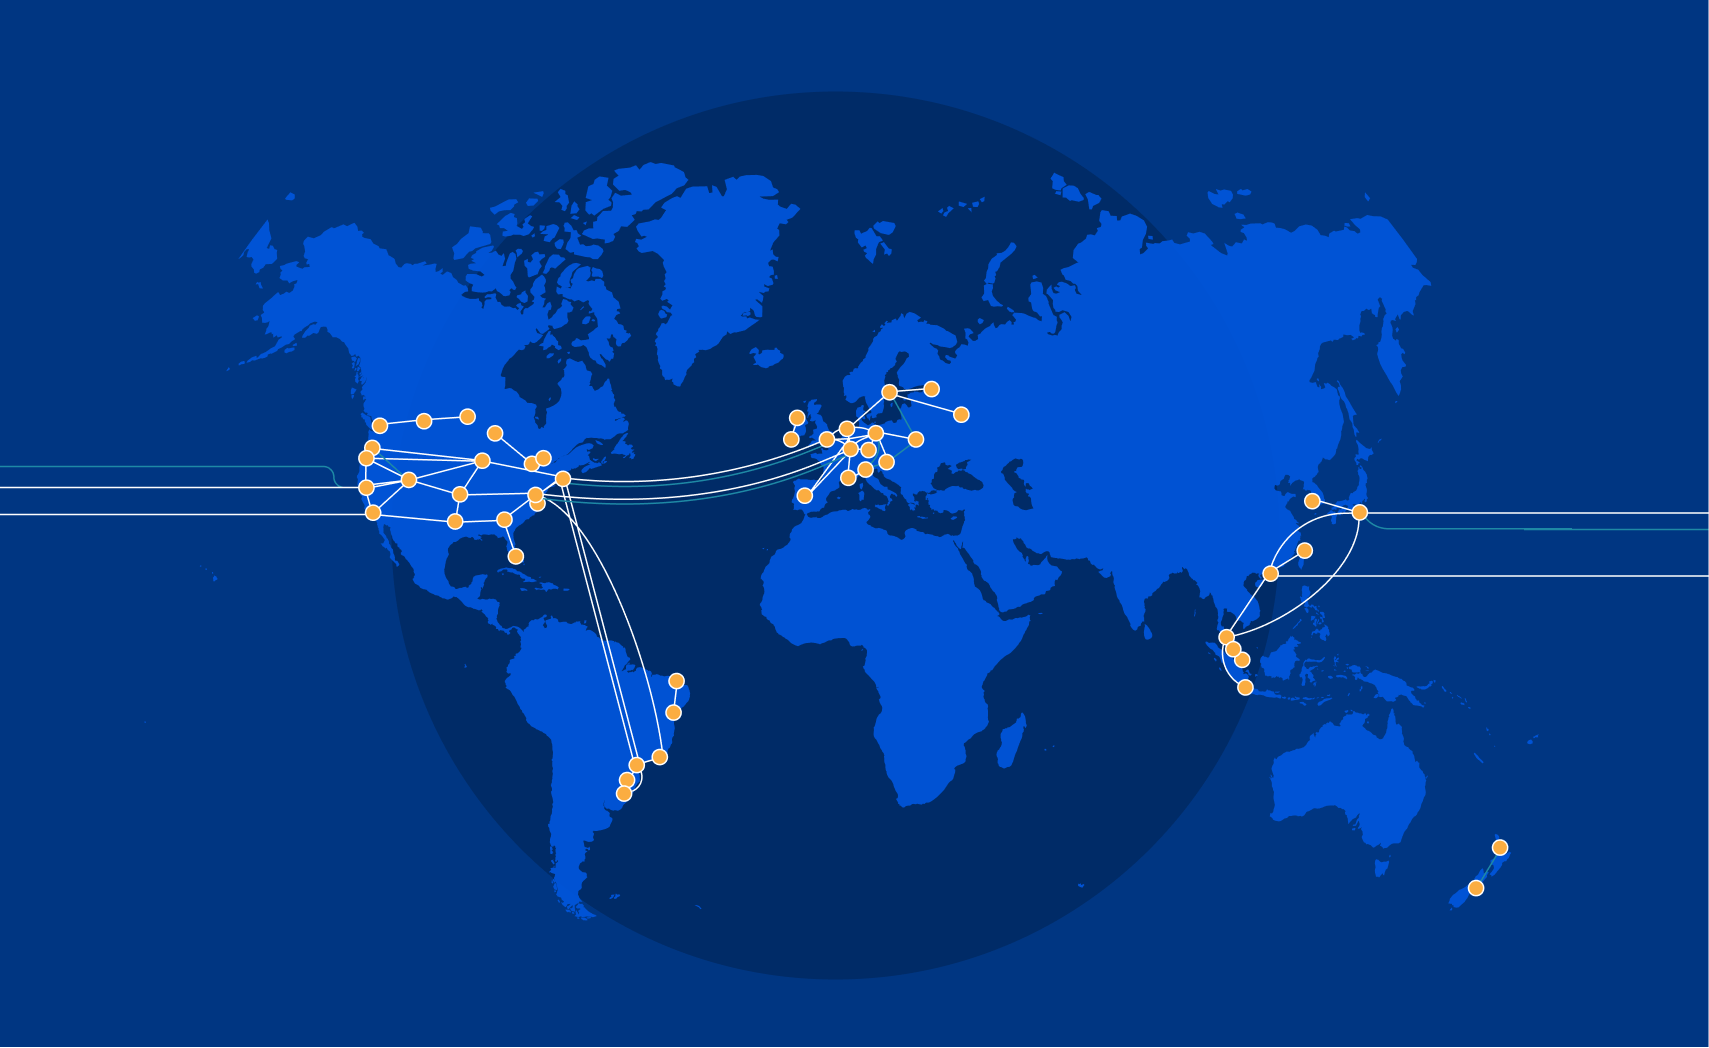
Cloudflare’s global network and backbone in 2026.

Cloudflare’s network recently passed a major milestone: we crossed 500 terabits per second (Tbps) of external capacity.

When we say 500 Tbps, we mean total provisioned external interconnection capacity: the sum of every port facing a transit provider, private peering partner, Internet exchange, or Cloudflare Network Interconnect (CNI) port across all 330+ cities. This is not peak traffic. On any given day, our peak utilization is a fraction of that number. (The rest is our DDoS budget.)

It’s a long way from where we started. In 2010, we launched from a small office above a nail salon in Palo Alto, with a single transit provider and a reverse proxy you could set up by changing two nameservers.

The early days of transit and peering

Our first transit provider was nLayer Communications, a network most people now know as GTT. nLayer gave us our first capacity and our first hands-on company experience in peering relationships and the careful balance between cost and performance.

From there, we grew city by city: Chicago, Ashburn, San Jose, Amsterdam, Tokyo. Each new data center meant negotiating colocation contracts, pulling fiber, racking servers, and establishing peering through Internet exchanges. The Internet isn’t actually a cloud, of course. It is a collection of specific rooms full of cables, and we spent years learning the nuances of every one of them.

Not every city was a straightforward deployment, having to deal with missing hardware, customs strikes, and even dental floss. In a single month in 2018, we opened up in 31 cities in 24 days: from Kathmandu and Baghdad to Reykjavík and Chișinău. When we opened our 127th data center in Macau, we were protecting 7 million Internet properties. Today, with data centers in 330+ cities, we protect more than 20% of the web.

When the network became the security layer 

As our footprint grew, customers asked for more than just website caching. They needed to protect employees, replace aging Multiprotocol Label Switching (MPLS) circuits, and secure entire enterprise networks. Instead of traditional appliances, we built systems to establish secure tunnels to private subnets and advertise enterprise IP space directly from our global network via BGP.

The scale of threats grew in parallel. In 2025, we mitigated a 31.4 Tbps DDoS attack lasting 35 seconds. The source was the Aisuru-Kimwolf botnet, including many infected Android TVs. It was one of over 5,000 attacks we blocked that day. No engineer was paged.


A decade ago, an attack of that magnitude would have required nation-state resources to counter. Today, our network handles it in seconds without human intervention. That is what operating at a 500 Tbps scale requires: moving the intelligence to every server in our network so the network can defend itself.

How our network responds to an attack

Here is what actually happens when an attack hits our network. Packets arrive at the network interface card (NIC) and immediately enter an eXpress Data Path (XDP) program chain managed by xdpd, running in driver mode. Among the first programs in that chain is l4drop, which evaluates each packet against mitigation rules in extended Berkeley Packet Filter (eBPF). Those rules are generated by dosd, our denial of service daemon, which runs on every server in our fleet. Each dosd instance samples incoming traffic, builds a table of the heaviest hitters it sees, and broadcasts that table to every other instance in the colo. The result is a shared colo-wide view of traffic, and because every server works from the same data, they reach the same mitigation decision.


When dosd detects an attack pattern, the resulting rule is applied locally via l4drop and propagates globally via Quicksilver, our distributed key-value (KV) store, reaching every server in every data center within seconds. Only after surviving l4drop do packets reach Unimog, our Layer 4 (L4) load balancer, which distributes them across healthy servers in the data center. For Magic Transit customers routing enterprise network traffic through our edge, flowtrackd adds a further layer of stateful TCP inspection, tracking connection state and dropping packets that don’t belong to legitimate flows.

The 31.4 Tbps attack we mitigated followed exactly this path. No traffic was backhauled to a centralized scrubbing center. No human intervened. Every server in the targeted data centers independently recognized the attack and began dropping malicious packets at line rate, before those packets consumed a single CPU cycle of application processing. The software is only half the story: none of it works if the ports aren’t there to absorb the traffic in the first place.

A distributed developer platform

Running code on every server in our network was a natural consequence of controlling the full stack. If we already ran eBPF programs on every machine to drop attack traffic, we could run customer application code there too. That insight became Workers, and later KV and Durable Objects.

Our developer platform runs in every city we operate in, not in a handful of cloud regions. In 2025, we added Containers to Workers, so heavier workloads can run at the edge too. V8 isolates and custom filesystem layers minimize cold starts. Your code runs where your users are, on the same servers that drop attack traffic at line rate via l4drop. Attack traffic is dropped before it reaches the network stack. Your application never sees it.

Forward-looking protocols: IPv6, RPKI, ASPA

We were early adopters of IPv6 and Resource Public Key Infrastructure (RPKI). BGP hijacks cause real outages and security breaches. RPKI allows us to drop invalid routes from peers, ensuring traffic goes where it is supposed to. We sign Route Origin Authorizations (ROAs) for our prefixes and enforce Route Origin Validation on ingress. We reject RPKI-invalid routes, even when that occasionally breaks reachability to networks with misconfigured ROAs.

Autonomous System Provider Authorization (ASPA) is next. RPKI validates who owns a prefix. ASPA validates the path it took to get here. RPKI is a passport check at the destination, confirming the right owner, while ASPA is a flight manifest check: it verifies every network the traffic passed through. A route leak is like a passenger who boarded in the wrong city; RPKI would not catch it, but ASPA will.

Current ecosystem adoption for ASPA looks like RPKI did in 2015. We were one of the first networks to deploy RPKI at scale, and today, 867,000 prefixes in the global routing table have valid RPKI certificates, up from near zero a decade ago. At our scale, the protocols we choose have real consequences for the broader Internet. We push for adoption early because waiting means more hijacks and more leaks in the meantime.

AI agents and the evolving Internet

AI has changed what it means to have a presence on the web. For most of the Internet’s history, traffic was human-generated, by people clicking links in browsers. Today, AI crawlers, model training pipelines, and autonomous agents now account for more than 4% of all HTML requests across our network, comparable to Googlebot itself. “User action” crawling, where an AI visits a page because a human asked it a question, grew over 15x in 2025 alone.

AI crawlers behave differently than browsers at the infrastructure level. Browsers load a page and stop. Crawlers instead fetch every linked resource at maximum throughput with no pause between requests. At our scale, distinguishing legitimate AI crawling from actual attacks is a real engineering problem. Our detection systems use a combination of verified bot IP ranges, TLS fingerprinting, behavioral analysis, and robots.txt compliance signals to make that distinction, and to give site owners the data they need to decide which crawlers to allow.

At the TLS layer, for example, a legitimate browser presents a ClientHello with a predictable set of cipher suites, extensions, and ordering that matches its declared User-Agent. A crawler spoofing that User-Agent but using a stripped-down TLS library will present a different fingerprint, and that mismatch is one of the signals our systems use to classify the request before it reaches the origin.

Help us build the next 500 Tbps

What started above a nail salon in Palo Alto is now a 500 Tbps network in 330+ cities across 125+ countries, where every server runs our developer platform and security services, not just cache. That is sixteen years of architectural decisions compounding, and we owe it to the 13,000+ networks and partners who peer with us. We are not done.

If you are a network operator, peer with us. Our peering policy and interconnection details are on PeeringDB. If you are interested in embedding Cloudflare infrastructure directly within your network, reach out to our team at [email protected], to join the Edge Partner Program.
Cloudflare Backbone: A Fast Lane on the Busy Internet Highway

Post Syndicated from Tanner Ryan original https://blog.cloudflare.com/cloudflare-backbone-internet-fast-lane/

Cloudflare Backbone: A Fast Lane on the Busy Internet Highway

Cloudflare Backbone: A Fast Lane on the Busy Internet Highway

The Internet is an amazing place. It’s a communication superhighway, allowing people and machines to exchange exabytes of information every day. But it’s not without its share of issues: whether it’s DDoS attacks, route leaks, cable cuts, or packet loss, the components of the Internet do not always work as intended.

The reason Cloudflare exists is to help solve these problems. As we continue to grow our rapidly expanding global network in more than 250 cities, while directly connecting with more than 9,800 networks, it’s important that our network continues to help bring improved performance and resiliency to the Internet. To accomplish this, we built our own backbone. Other than improving redundancy, the immediate advantage to you as a Cloudflare user? It can reduce your website loading times by up to 45% — and you don’t have to do a thing.

The Cloudflare Backbone

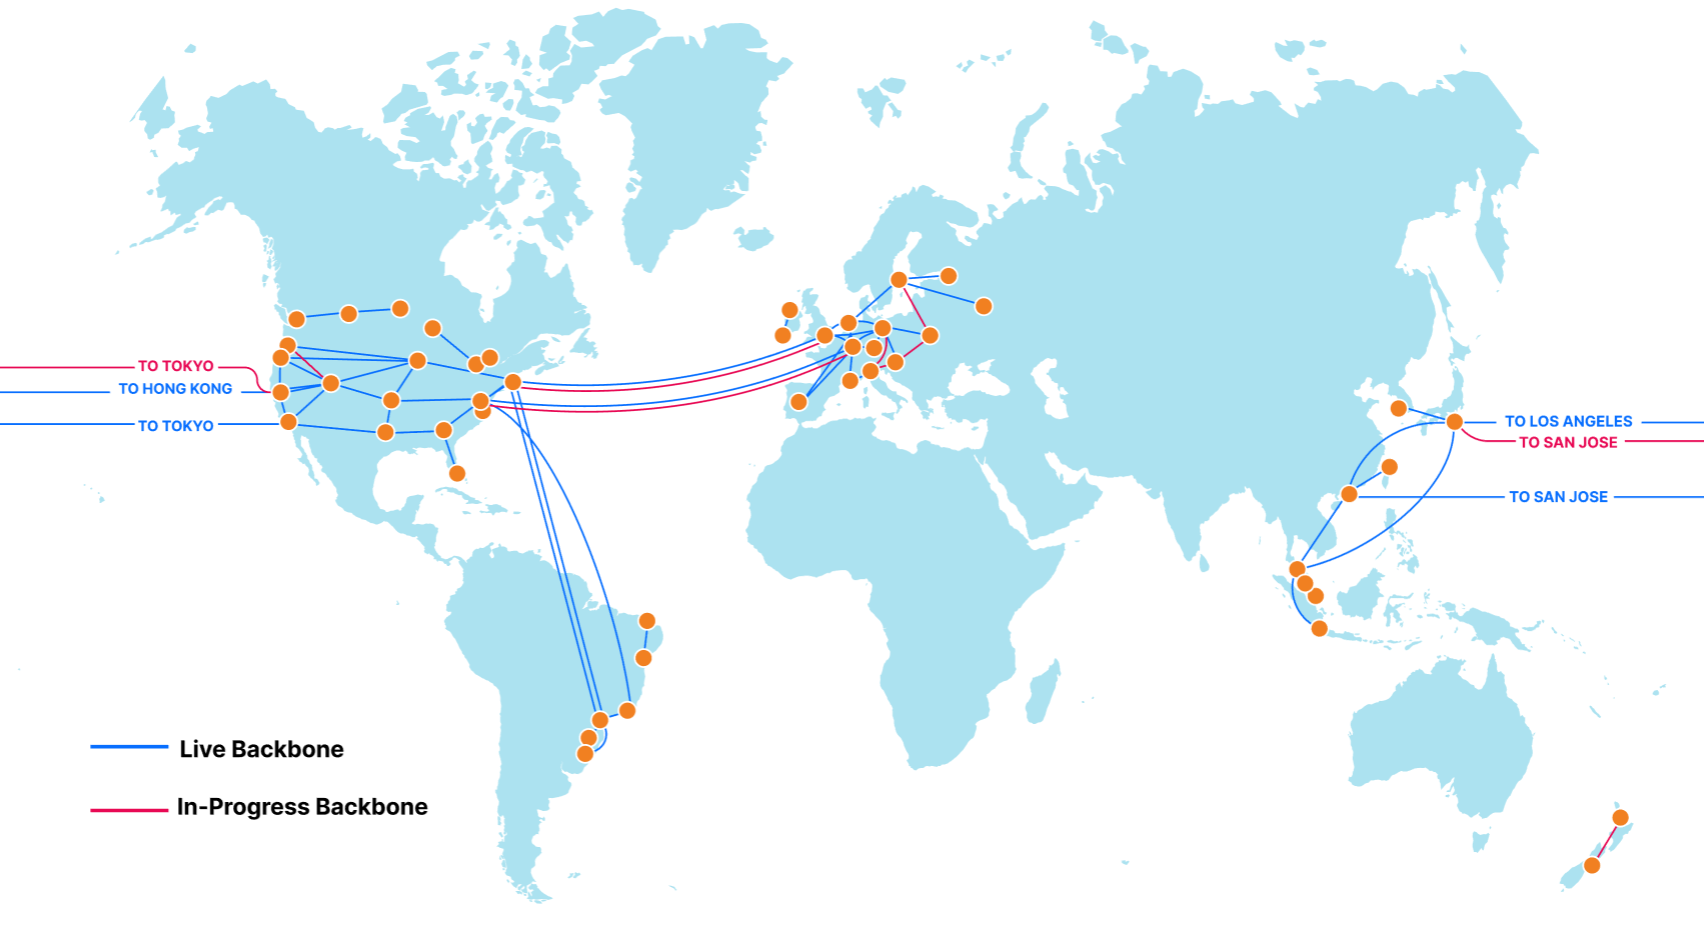
We began building out our global backbone in 2018. It comprises a network of long-distance fiber optic cables connecting various Cloudflare data centers across North America, South America, Europe, and Asia. This also includes Cloudflare’s metro fiber network, directly connecting data centers within a metropolitan area.

Cloudflare Backbone: A Fast Lane on the Busy Internet Highway

Our backbone is a dedicated network, providing guaranteed network capacity and consistent latency between various locations. It gives us the ability to securely, reliably, and quickly route packets between our data centers, without having to rely on other networks.

This dedicated network can be thought of as a fast lane on a busy highway. When traffic in the normal lanes of the highway encounter slowdowns from congestion and accidents, vehicles can make use of a fast lane to bypass the traffic and get to their destination on time.

Our software-defined network is like a smart GPS device, as we’re always calculating the performance of routes between various networks. If a route on the public Internet becomes congested or unavailable, our network automatically adjusts routing preferences in real-time to make use of all routes we have available, including our dedicated backbone, helping to deliver your network packets to the destination as fast as we can.

Measuring backbone improvements

As we grow our global infrastructure, it’s important that we analyze our network to quantify the impact we’re having on performance.

Here’s a simple, real-world test we’ve used to validate that our backbone helps speed up our global network. We deployed a simple API service hosted on a public cloud provider, located in Chicago, Illinois. Once placed behind Cloudflare, we performed benchmarks from various geographic locations with the backbone disabled and enabled to measure the change in performance.

Instead of comparing the difference in latency our backbone creates, it is important that our experiment captures a real-world performance gain that an API service or website would experience. To validate this, our primary metric is measuring the average request time when accessing an API service from Miami, Seattle, San Jose, São Paulo, and Tokyo. To capture the response of the network itself, we disabled caching on the Cloudflare dashboard and sent 100 requests from each testing location, both while forcing traffic through our backbone, and through the public Internet.

Now, before we claim our backbone solves all Internet problems, you can probably notice that for some tests (Seattle, WA and San Jose, CA), there was actually an increase in response time when we forced traffic through the backbone. Since latency is directly proportional to the distance of fiber optic cables, and since we have over 9,800 direct connections with other Internet networks, there is a possibility that an uncongested path on the public Internet might be geographically shorter, causing this speedup compared to our backbone.

Luckily for us, we have technologies like Argo Smart Routing, Argo Tiered Caching, WARP+, and most recently announced Orpheus, which dynamically calculates the performance of each route at our data centers, choosing the fastest healthy route at that time. What might be the fastest path during this test may not be the fastest at the time you are reading this.

With that disclaimer out of the way, now onto the test.

Cloudflare Backbone: A Fast Lane on the Busy Internet Highway

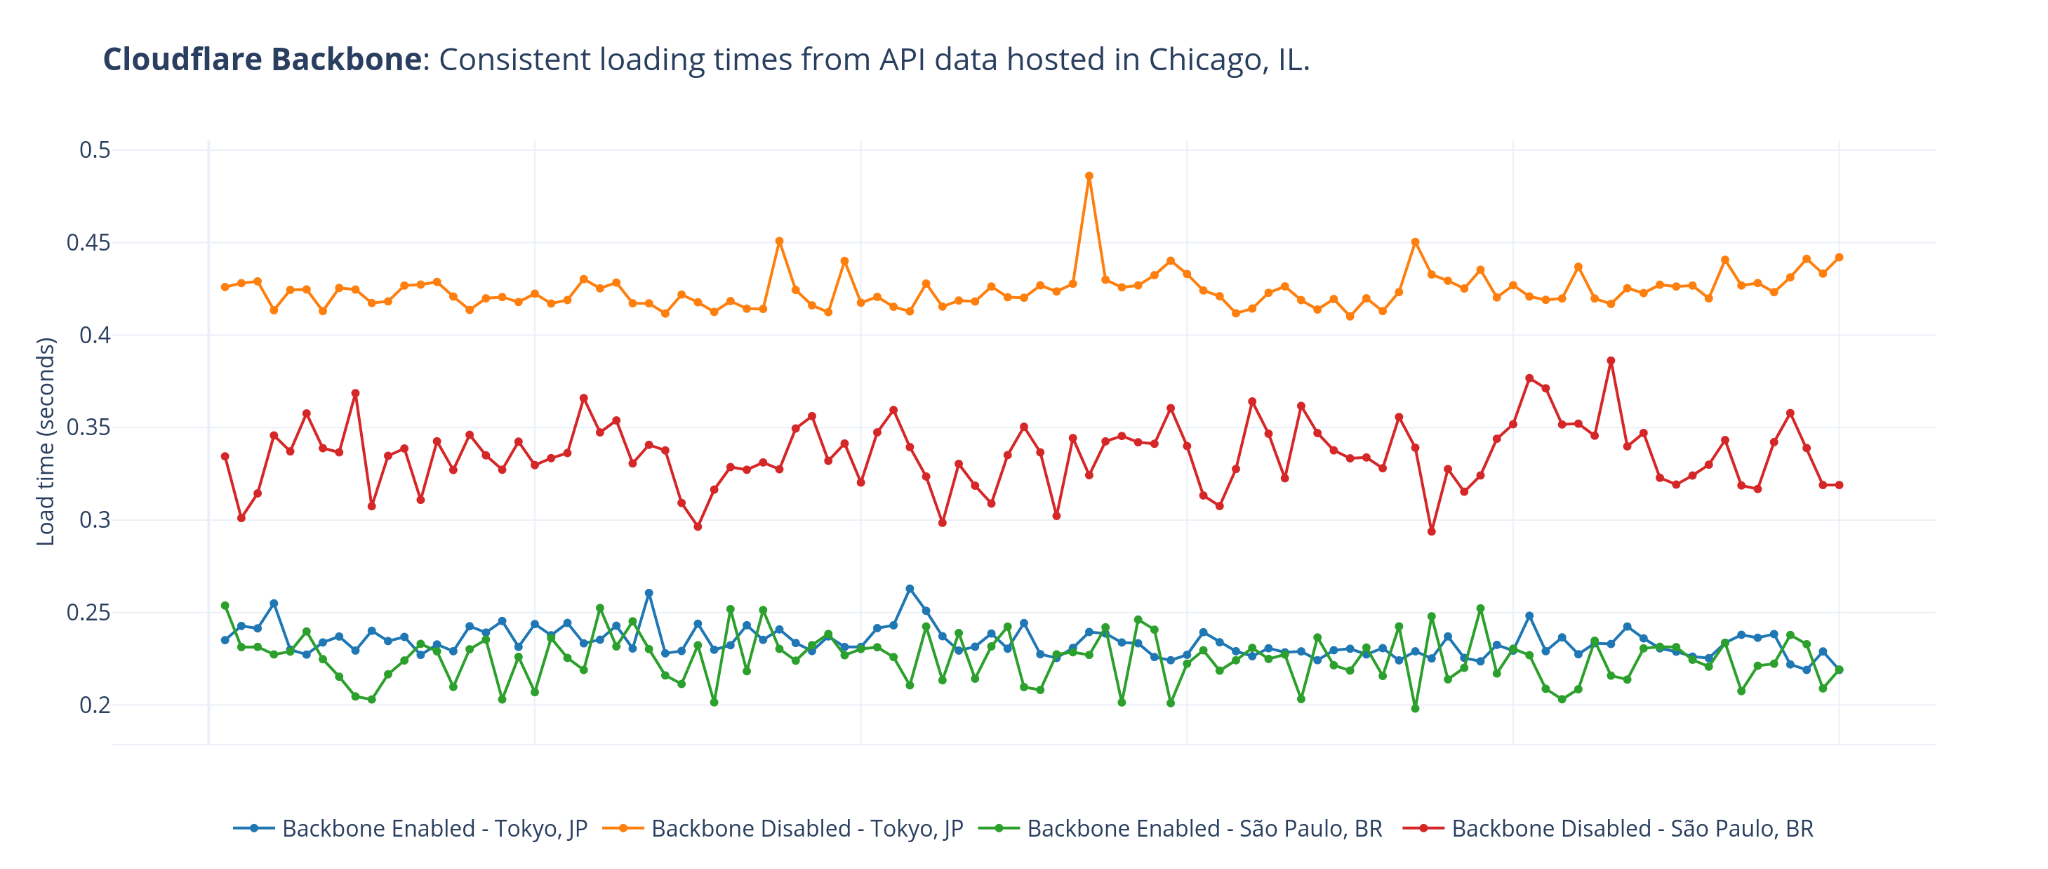
With the backbone disabled, if a visitor from São Paulo performed a request to our service, they would be routed to our São Paulo data center via BGP Anycast. With caching disabled, our São Paulo data center forwarded the request over the public Internet to the origin server in Chicago. On average, the entire process to fetch data from the origin server and return to the response to the requesting user took 335.8 milliseconds.

Once the backbone was enabled and requests were created, our software performed tests to determine the fastest healthy route to the origin, whether it was a route on the public Internet or through our private backbone. For this test the backbone was faster, resulting in an average total request time of 230.2 milliseconds. Just by routing the request through our private backbone, we improved the average response time by 31%.

We saw even better improvement when testing from Tokyo. When routing the request over the public Internet, the request took an average of 424 milliseconds. By enabling our backbone which created a faster path, the request took an average of 234 milliseconds, creating an average response time improvement of 44%.

Visitor Location Distance to Chicago Avg. response time using public Internet (ms) Avg. response using backbone (ms) Change in response time
Miami, FL, US 1917 km 84 75 10.7% decrease
Seattle, WA, US 2785 km 118 124 5.1% increase
San Jose, CA, US 2856 km 122 132 8.2% increase
São Paulo, BR 8403 km 336 230 31.5% decrease
Tokyo JP 10129 km 424 234 44.8% decrease

We also observed a smaller deviation in the response time of packets routed through our backbone over larger distances.

Cloudflare Backbone: A Fast Lane on the Busy Internet Highway

Our next generation network

Cloudflare is built on top of lossy, unreliable networks that we do not have control over. It’s our software that turns these traditional tubes of the Internet into a smart, high performing, and reliable network Cloudflare customers get to use today. Coupled with our new, but rapidly expanding backbone, it is this software that produces significant performance gains over traditional Internet networks.

Whether you visit a website powered by Cloudflare’s Argo Smart Routing, Argo Tiered Caching, Orpheus, or use our 1.1.1.1 service with WARP+ to access the Internet, you get direct access to the Internet fast lane we call the Cloudflare backbone.

For Cloudflare, a better Internet means improving Internet security, reliability, and performance. The backbone gives us the ability to build out our network in areas that have typically lacked infrastructure investments by other networks. Even with issues on the public Internet, these initiatives allow us to be located within 50 milliseconds of 95% of the Internet connected population.

In addition to our growing global infrastructure providing 1.1.1.1, WARP, Roughtime, NTP, IPFS Gateway, Drand, and F-Root to the greater Internet, it’s important that we extend our services to those who are most vulnerable. This is why we extend all our infrastructure benefits directly to the community, through projects like Galileo, Athenian, Fair Shot, and Pangea.

And while these thousands of fiber optic connections are already fixing today’s Internet issues, we truly are just getting started.

Want to help build the future Internet? Networks that are faster, safer, and more reliable than they are today? The Cloudflare Infrastructure team is currently hiring!

If you operate an ISP or transit network and would like to bring your users faster and more reliable access to websites and services powered by Cloudflare’s rapidly expanding network, please reach out to our Edge Partnerships team at [email protected].