Tag Archives: Workers AI

When scanners miss the attack: how Cloudflare Client-Side Security protects storefronts

Post Syndicated from Juan Miguel Cejuela original https://blog.cloudflare.com/client-side-security-finds-4-malicious-campaigns/

A modern storefront can look perfectly healthy while malicious JavaScript works underneath: siphoning affiliate revenue, hijacking searches and clicks, tampering with analytics, or asking a remote server what to execute next. Pages load, products appear, and checkout works — yet the browser may be quietly doing something the site owner never authorized.

That is the blind spot our Client-Side Security machine learning (ML) model is built to expose. This post follows four operations, spanning eight payloads, that our Page Shield ML uncovered in the wild. 

The detection of these malicious payloads was automated; humans verified each finding only after the system had flagged it. When we afterward reviewed the campaigns using security scanning tools, seven of the eight payloads were entirely absent from VirusTotal, and URLScan returned no malicious verdict for any of them. Page Shield ML, meanwhile, caught all eight in live traffic.

For instance, while security research documented the broader Lnkr family years earlier, one specific payload version sat indexed by URLScan for nearly two and a half years with “No classification,” including during a direct scan in January 2024. Only in this case had VirusTotal ingested the payload earlier: while it currently flags the script as malicious, public history does not reveal when that verdict was first assigned. Meanwhile, Page Shield ML independently surfaced those exact bytes live on an online retailer's storefront. More broadly, a hash can be known long before the code behind it is classified as malicious. If your defense waits for that label, you are already late. You need ML that can unravel the JavaScript itself and judge it at scale.

Indeed, seeing a file is not the same as understanding it. The tricky part was that the four operations shared no universal signature or common concealment technique. One remained dormant unless the device, country, time, referrer, or browser state matched what it was waiting for. Another concealed a clickless affiliate request within an invisible iframe. Others intercepted clicks, suppressed monitoring, or conditionally loaded additional code from remote servers. To catch them, you have to watch how those pieces work together: when the script wakes up, what it hides, what it intercepts, and what it fetches next. Checking the page once is not enough; as these cases show, such scripts are built to stay quiet until the right victim shows up. That is why ongoing browser visibility makes the difference between catching an attack and missing it entirely.

How we detect and label JavaScript at scale

The same GNN (graph neural network) that flagged the four operations in this post had already caught malicious npm packages and an in-the-wild Magecart payment skimmer. The GNN does not treat JavaScript as a flat chunk of text; it reasons through the code as a graph: a syntax tree connecting code symbols and exposing what calls what, what the attacker tried to bury, and what still phones home. That structure helps it recognize suspicious patterns across minification, renaming, and some obfuscation without relying on a known URL or byte signature. 

The few scripts that the GNN flags as malicious (under 0.3% of all analyzed traffic) go to a lightweight large language model (LLM) on Workers AI for a live second opinion. This further reduces false positives while keeping recall high. When the LLM corroborates the GNN, customers are alerted.

To investigate the most complex scripts at scale, we use a cohort of frontier models, which we call teachers (an ensemble of automated judges). The cohort draws leading models from around six different families, including open-weight models running on Workers AI. We spin up each as an agent to analyze the same suspicious script in its own fresh, independent session. When useful, their agentic tool access lets them use a restricted JavaScript evaluator to unpack small snippets and reveal concealed behavior. We will soon extend this workflow with Cloudflare Sandbox for deeper analysis in isolated environments.

The frontier models sometimes disagree, especially on the most intricate scripts. We treat that disagreement as signal, not noise. Each label becomes a vote, weighted by the model's score in the Artificial Analysis Intelligence Index, producing a probability distribution over four labels: benign, payment skimming (magecart), other malware, and cryptomining. Human reviewers therefore need only examine scripts flagged as malicious or lacking a clear two-thirds majority. We then feed those label distributions back into GNN training, helping it distinguish ever more nuanced cases. This feedback loop is still partly manual, though we are starting to automate it.

Four malicious JavaScript operations we caught

These four operations do very different things, from commission theft to stolen analytics on shoppers the store already paid to acquire. Stealing a commission is not like skimming a credit card; likewise, hijacking search is not like stealing a password. If an ML model only knows one of those tricks, it will sleep through the others. Instead, our Page Shield ML has to stay attuned to every kind of hostile behavior. 

Now, let’s dig deeper into each operation and how it worked.

Operation 1: The after-hours affiliate-commission hijacker

Picture a quiet Sunday afternoon: a shopper on a phone taps a product. Instead of following the tap normally, the script opens a product or campaign landing page from an attacker-preselected list in a new tab and sends the original tab through an affiliate route. The storefront still appears to work. If the shopper completes a purchase (either then or later), the detour hijacks the attribution, crediting the sale (and any resulting commission) to an account that did not earn the referral.

What the shop lost

The shop could pay an unearned commission to an account that did not bring the shopper. Worse, if a legitimate partner had made the referral, the forced request could misattribute it, diverting credit and a potential payout from the partner who did the work. The damage could outlast one commission: partners who stop trusting the attribution system may also stop trusting the retailer behind it.

Attack chain

Qualified mobile visitor → intercepted product tap → script-selected page opens in new tab + original tab follows attacker’s affiliate route

How it stayed hidden

We found five related script builds: two active and three paused when captured. Each active variant uses a different set of gates before it acts, checking things like the visitor’s device and local time, whether the trick has run recently, whether a product button has appeared, and whether someone actually clicks it. That maze of rules keeps the malicious behavior out of sight during a brief automated visit unless the variant’s specific conditions are met. The active scripts use a MutationObserver (a JavaScript API) to watch for product tiles and buttons that dynamically appear after the page is first loaded. This lets them intercept clicks on those late-arriving elements, while a crawler that loaded the HTML once and stopped there could miss the redirect path entirely.

In the active later variants, the script intercepts a qualifying click and writes a three-day cooldown to localStorage (staying dormant on that device for days). It then executes a dual-tab maneuver: popping an attacker-chosen product page into a fresh tab to keep the shopper engaged, while the original tab takes a quick, unnoticed round-trip through the attacker's affiliate tracking link and back to the shop, to plant the attacker’s attribution cookie in the background. Console masking and self-defending source checks make inspection harder, while the cooldowns and narrow schedules limit how often the malicious path can appear during otherwise normal shopping.

The following sanitized excerpt shows how the payload hooks dynamic product tiles and executes the dual-tab detour. We simplified identifiers, reformatted the code, and neutralized destination URLs for readability.

The paused builds showed how the campaign could go dark without removing the script. Their embedded configuration set status: "paused", so they exited before installing click handlers. These paused scripts carried different per-shopper cooldown configurations (3, 4, and 5 days). One of the paused scripts even recorded a version-history comment explicitly documenting that the campaign was paused after Black Friday.

To reach visitors in the first place, the operation leveraged the site's marketing supply chain: the third-party scripts and tag managers embedded by e-commerce sites to track ad campaigns and analytics. One confirmed delivery path ran through two otherwise ordinary tag managers: Google Tag Manager → another tag manager → malicious script. That is how the payload reached the browser, not proof that either tag manager was compromised.

The attacker even disguised the domain hosting the script to pass a quick marketing review. One delivery host hid in plain sight: adtargett[.]com differed by a single “t” from adtarget[.]com, an advertising domain registered in 1998. The lookalike was registered in 2025 and, when we checked, its homepage called itself “Adtarget.com – Performance Marketing Agency.” This is typosquatting: by mimicking a real ad agency, the host blended in with routine marketing tags, quietly serving the malicious payload that hijacked shopper clicks and redirected them through affiliate payout links.

Operation 2: The clickless affiliate theft

While the first scam still needed a click, this one requires even less. A shopper can open a booking page, linger over the product options, and never touch an ad. In the background, however, the script might have already sent an affiliate request that could make a later sale look as though someone else had referred the shopper. Indeed, when the script’s conditions are met, the payload sends that request through a hidden iframe or a link that clicks itself.

What the shop lost

For the affected tourism business, the attack could corrupt the economics of customer acquisition: a legitimate booking or purchase could be credited to an unearned affiliate account. The code proves covert, automated affiliate requests, but whether any specific request resulted in completed attribution, account crediting, or paid commission in practice remains unobserved.

Attack chain

Time-gated browser → covert affiliate request (off-screen iframe) → 1-hour throttle cookie → when blocked, automated hidden-link click fallback

How it stayed hidden

The script conceals the affiliate request in two layers: selective execution (a pre-flight network gate and hourly schedule), and stealth delivery (an off-screen iframe). The first layer is surprising because its country labels are disconnected from actual geography: neither the shopper’s nor the shop’s location drives the choice.

First, the script calls a public IP-based geolocation service but ignores everything it returns, including the shopper’s country. We could not determine why it required a successful response while ignoring the returned data; this may have been intended to confuse investigators or simply been a remnant of an earlier version. Interestingly, if the geolocation request fails, the script silently stops; its promise chain ends with .catch(() => {}). Although intent is unproven, this fail-closed behavior could help the script evade network-restricted sandboxes.

Next, instead of using the fetched geolocation data, the payload contains three TradeDoubler (an affiliate-marketing network) configuration objects labelled {AU, US, and UK}. These settings blocks are embedded in the code, and each contains an affiliate URL and start and end times. The script computes Asia/Kolkata time in JavaScript, checks those configured time windows, then applies fixed odd/even-hour rules to choose one of the three or else skip the affiliate request for that run. The choice is deterministic. 

Together, the schedule and browser-state checks create time-gated selective execution, a form of cloaking. When those conditions do not line up, the affiliate behavior stays dormant, so a one-off inspection can miss it.

Once the script chooses a configuration, it writes a local cookie named affiliateClicked_<market> as a one-hour retry throttle so it will not re-fire for that region right away (this is a client-side throttle to avoid noise, not an affiliate-network attribution cookie). Next, it loads that affiliate URL in an off-screen iframe with the referrer suppressed. The iframe is the primary delivery path, but it carries an aggressive fallback: if the iframe errors or fails to finish loading after one to two seconds, the script creates a hidden link (<a>) without a target attribute and clicks it programmatically, which could navigate the user's active tab. To the qualifying shopper, nothing seems out of place: they never see an ad, never have to click, and can close the tab as if nothing happened.

As for the script’s obfuscation, it is simple but effective: even property names are assembled one character at a time. The following sanitized excerpt shows the payload creating an invisible off-screen iframe. We renamed key identifiers and reformatted the code for readability. The destination has been removed.

Operation 3: The old search saboteur, now storefront backdoor

Years ago, the Lnkr malware family made the news by hiding inside shady browser extensions, intercepting Google and Bing searches to redirect results and pocket ad money. Now, attackers repurposed the codebase to plant a backdoor into an online retailer’s website.

Because the script was running on a shop rather than a search engine, its old redirect tricks stayed dormant. This time, the script was used to send telemetry back to the attacker. More dangerously, it gave the attacker a remote doorway to arbitrarily download and run fresh JavaScript in customers' browsers whenever they wanted, without touching a single file on the server. It even carried an old trick from its extension days: shutting itself off if someone typed words like “virus” or “popup” into Google. From the outside, the store kept selling without a hint that anything was wrong.

What the shop lost

The shop lost control over what code runs in its customers' browsers. Attackers were secretly tracking visitors' sessions and had a direct backdoor to push and run any JavaScript they wanted on the storefront at any time.

Attack chain

HTML-referenced script → analyst evasion gates → parallel host-gated branches (dormant search vs. live backdoor) → arbitrary remote JavaScript execution

How it stayed hidden

Unlike campaigns delivered through tag managers, this script was directly embedded into the merchant’s HTML. We could not determine the exact initial intrusion vector; in practice, direct HTML insertions usually happen through compromised store admin credentials, an unauthorized template edit, or an infected third-party theme or plugin.

Under the hood, the script is a modular toolkit carrying both active and dormant code. Its older modules (transparent click overlays, search-engine query interceptors, extension-store link rewriters, and redirects for typosquatted domains, like buking[.]com instead of booking[.]com) only wake up on specific target sites, so they stayed turned off on this storefront. Several embedded domains (sugabit[.]net, votetoda[.]com, cdnpps[.]us, and telemetry endpoint hanstrackr[.]com) sat inside these disabled modules.

On the shop, the active branches focused on evasion, telemetry, and remote control:

  • Playing dead for security researchers. An evasion trick inherited from its browser-extension days: the script monitored search inputs and URL queries for telltale adware terms. Searching one security keyword paused the script for that visit. Searching two or more wrote a persistent opt-out record to localStorage, permanently silencing the script on that analyst's machine so repeated tests would find nothing. While originally built to dodge analysts on search engines, as far as we could determine, this check was hard-coded specifically to Google search URLs and remained dormant on the merchant's storefront.
  • Dynamic remote code execution. The script didn't need to modify the storefront to change its behavior. While the hardcoded domain names (scrprime[.]com, youronlinesearches[.]com, jullyambery[.]net) remained identical to older captures, what those endpoints returned was entirely up to the attacker. The script could phone home visitor telemetry, ask those servers for new instructions, and pull down fresh JavaScript directly into the shopper's browser. Effectively, this gave attackers a live backdoor to run arbitrary code on the storefront. We could not determine what second-stage payloads were served in practice.

All in all, a static snapshot of the site showed only the normal storefront, while the underlying state checks, anti-analysis traps, and remote-loading branches exposed the backdoor.

Operation 4: The paid-mobile cloaker

The shop already paid to bring this visitor in from a mobile ad or marketing campaign. The malicious script lets that visit through, then cuts off the merchant's visibility. Analytics go dark, the live support chat vanishes, and a rogue observer starts recording telemetry on the very session the store just bought. 

Behind the scenes, the payload refuses to run unless that visit matches an elaborate set of conditions: the exact target storefront, a narrow mobile screen, and a campaign tag during the first two pages of the visit. It stays dormant on laptops, corporate networks, cloud providers, and VPNs, so the engineers most likely to debug the page never see it fire. The script also stays dormant across selected US cities and regions, backed by a handcrafted denylist of 325 IP strings to dodge automated scanners and security analysts. Only then does the script attempt to tear down the shop’s monitoring, substitute replacement advertising and analytics identities, and phone home. A second look from the wrong device or network will never trigger it. All the while, the storefront keeps selling.

What the shop lost

For a direct-to-consumer retailer, the malware specifically targeted high-value traffic the store had paid to acquire through paid-search and marketing campaigns (ppc, cpc, sms, paid). Those customers could still buy. Yet the shop faced three clear threats: diverted advertising attribution and unearned publisher payouts, the loss of critical session analytics across nine observability tools, and the suppression of the help chat and contact form (preventing shoppers from asking questions or reporting anomalies). Dynamic analysis in a sandboxed browser environment confirmed that the replacement analytics script loaded and fired a tracking beacon (an invisible network request sent to log visitor activity), but whether the attacker successfully captured session telemetry or diverted ad revenue in practice remains unproven.

Attack chain

Campaign-tagged mobile arrival → multi-tier cloaking & network gates → monitoring sabotaged → advertising, analytics, and support controls rewritten 

How it stayed hidden

To blend into the store's marketing supply chain, the attacker delivered the payload from sdk-amazonaws[.]com, a lookalike domain registered in 2024 and wholly unaffiliated with the official Amazon Web Services domain (amazonaws.com, registered in 2005). To compound the deception, the attacker prefixed the domain with a subdomain mimicking a popular e-commerce marketing platform too. This stacked, double-trusted-brand typosquat forged a convincing disguise, engineered to slip past quick tag reviews. Neither Amazon Web Services nor the impersonated marketing platform was involved in the attack or suffered any compromise.

Once loaded in the browser, the script executed an exceptionally dense gauntlet of cloaking gates before triggering its main payload:

  • Target host and browsing context. The script verified that window.location.hostname matched the specific merchant host it was built to target (exiting immediately anywhere else), ensured the current window was top-level (not an embedded iframe), and checked that the path did not contain /challenge. It also verified that tracking marker cookies (_cart_dr and logoalt) were not already present in the browser.
  • Device and campaign filtering. The visitor's viewport width had to be narrower than 477 pixels (a handheld smartphone). Furthermore, the visitor had to arrive via a first-touch (the visitor's initial referral) campaign tagged with one of six specific UTM mediums (Urchin Tracking Module, standard URL tags used to track marketing campaigns): ppc, cpc, sms, paid, flow, or campaign. It also had to be the first or second page load of their session. Curiously, while the code contained a nominal non-UTM path, it required the session page count to be simultaneously greater than -1 and less than -2 (a mathematical impossibility that left that branch completely unreachable). This could be yet another diversion technique or a code change leftover.
  • The "random" gate that always passed. The code featured what looked like a probabilistic throttle (Math.random() <= threshold) to make execution appear intermittent. However, when we solved the deobfuscated arithmetic, the threshold reduced to exactly 1. Because JavaScript's Math.random() always returns a value strictly below 1, this gate always evaluates to true. Like the unreachable non-campaign branch, this is a condition that never actually decides anything. It may be a leftover throttle, or purposeful camouflage for anyone reading the obfuscated math. Either way, the captured payload never used it to skip a qualifying visitor.
  • Third-party IP intelligence. The script queried an external third-party IP intelligence API using an embedded key. It required a U.S. mobile consumer connection, while immediately bailing out if the response flagged a business network, hosting facility, cloud provider, bogon, Tor exit node, VPN, proxy, relay, or general threat indicator.
  • Geographic exclusions. The payload did not activate for visitors from specific regions (US-NY, US-CA, and US-NHDD) or from cities named San Francisco, Plymouth, Compton, Hopkinton, and Lafayette.
  • The 325-entry IP substring trap. The script checked the visitor's IP against an embedded denylist containing 325 full IPv4 address strings. After deduplication, these represented 313 unique addresses across 249 distinct three-octet prefixes. Rather than performing structured CIDR (Classless Inter-Domain Routing) subnet matching, the author simply stripped the final octet from the visitor's IPv4 address and ran a raw substring search: !denylistString.includes(visitorPrefix).

In stripped-down pseudocode, the multi-layer primary activation funnel looks like this:

Sabotaging observability and hijacking identities:

Only after every primary gate passed did the script execute its payload:

  • Blinding monitoring tools. It searched the DOM and removed script tags for nine different observability and analytics services: Lucky Orange, Segment, Optimizely, New Relic, Bugsnag, LogRocket, Hotjar, Microsoft Clarity, and the store's Google Tag Manager container (GTM-<redacted>). In remaining inline scripts, it string-replaced references to these tools with undefined dummy identifiers (hji0) so calls to them failed silently, attempting to blind the store's error reporting and monitoring.
  • Suppressing customer support. It injected CSS and removed elements to hide its support-chat and contact-form containers, cutting off the customer's direct line to store support.
  • Replacing advertising and analytics identities. It purged Google Ads globals (google_ad_modifications, adsbygoogle), tore down existing ad slots (ca-pub-<original>), and loaded Google Ads under a replacement publisher ID (ca-pub-<replacement>). It then injected a new Microsoft Clarity session-replay script configured with a rogue, replacement project ID.

Simpler independent beacons and the 600-day marker:

In sharp contrast to the elaborate primary cloak, the payload also contained secondary beaconing branches (standalone routines that quietly ping an external server to confirm a visit) that completely bypassed the viewport, hostname, campaign, geography, and IP gates. If the visitor was on their second page or beyond, the script wrote a persistent cookie (_cart_dr=1) with an expiry of exactly 600 days (51,840,000,000 milliseconds) and fired an invisible zero-pixel image request to a remote telemetry endpoint on maper[.]info (a tracking beacon used to log that the browser reached this step).

A separate branch checked for an alternate marker (_logo_alt), which would trigger a second telemetry .png beacon (a cookie this script looked for, but never wrote itself; likely planted by a companion script). This gave the attacker a simple, persistent hit-counter to log basic traffic for all visitors (IP and User-Agent logged at the endpoint) across the entire store, while keeping their high-risk ad-hijacking routines strictly hidden behind the mobile cloak (high-value paid arrivals). It shows why analyzing only one visible effect does not reveal the full reach of a multi-purpose payload.

Indicators of Compromise (IOCs)

We are publishing these indicators to help security teams and researchers detect and hunt these campaigns across their own environments. All indicators are drawn directly from captured payloads and their network connections. Listed URLs are defanged. Some indicators have been withheld or generalized because publishing them could inadvertently divulge the identities of affected organizations. Listed domains reflect infrastructure observed participating in the delivery, redirection, or telemetry chain during these attacks; inclusion does not imply that a shared service or hosting provider is exclusively malicious.

Four lessons for defenders

Taken together, the operations tell one escalating story: attackers changed the objective, delivery path, and disguise, but the browser still had to execute their logic. Four lessons stand out.

Behavior beats signatures. These operations pursued different forms of monetization and manipulation, but every payload still had to act in the browser: observe events, inspect state, alter the page, schedule work, make network requests, or load another stage. That is what structural analysis looks for: the logic a hostile payload must carry, even as URLs, signatures, and objectives change.

Selective execution is part of the attack, not a footnote. Device, time, geography, referrer, session, network, and cooldown gates can all defeat a crawler that visits once and takes a static snapshot. Continuous visibility matters because an attack may appear only to one browser, in one state, at one moment. 

Obfuscation raised the cost of analysis, but in these cases it did not prevent detection. Self-defending loops, console suppression, debugger traps, rotated string tables, and dead branches complicated analysis. Page Shield ML still surfaced all four operations despite those barriers. Fast in-house models surface the suspicious code at scale, while frontier models investigate the hardest cases. Their disagreements highlight the trickiest obfuscation and logic, helping us narrow our focus.

Context completes the picture. Code that looks ordinary in isolation can reveal its malicious role once defenders link static analysis with dynamic context: how it arrived, which browser state activated it, what connections it opened, and what it actually did at runtime.

Continuous visibility into client-side execution

These four operations relied on different layers of misdirection, but they all shared one constraint: their JavaScript had to execute in the browser. Public scanners and static crawls can miss gated behavior. Continuous observation helps clarify what the code actually does when real visitors interact with the page

Cloudflare Client-Side Security provides that visibility across all plans. You can turn on Continuous script monitoring under Security settings to track first- and third-party scripts on your storefront, while automated malicious-script detection and alerting are available with Client-Side Security Advanced. You can review script activity and manage detections directly in the Cloudflare dashboard.

Unifying Workers AI and AI Gateway into a single AI control plane

Post Syndicated from Michelle Chen original https://blog.cloudflare.com/workers-ai-gateway-unification/

AI Gateway and Workers AI first started as distinct products, but over time, we noticed our users were converging. With AI Gateway, you can proxy requests to any model provider and get built-in observability, logging, access, and security. On Workers AI, we host models on the GPU infrastructure that we manage, exposing an API endpoint you can leverage to access inference-as-a-service. 

The architecture of these products looks different, but to an end user, it achieves the same goal: connecting you to models with a sophisticated control plane. Today, we're excited to share our plans on how these products converge into one unified path, so you can connect to any model provider (including Workers AI), while managing things like observability, billing, security, and logging from a single control plane.

It’s the next step toward some big plans we have — read on to learn what a unified control plane means for the future of model routing.

Merging the binding and API

We've been hinting at the fact that these products are becoming more unified through our entrypoints: the Workers binding and the REST API. We have an AI binding that you can use to call AI Gateway and Workers AI. There's no concept of a separate AI Gateway and Workers AI binding: it all goes through the same path. We shipped the idea of a “default” gateway a few months ago, so that if you have never set up an AI Gateway before, you could still automatically inherit the AI Gateway observability and logging. Of course, you can still specify your own gateway if you'd like to split up applications into multiple projects.

Here's what the binding call looks like, if you are calling Workers AI via AI Gateway:

We’ve also announced a single unified REST API — the /ai/ endpoint that allows you to make similar calls to Workers AI via AI Gateway.

Doing this allows us to unify the entrypoints to AI Gateway and Workers AI, so you don't need to make a choice between which product to use first: it all comes with batteries included.

Automatic observability and control for all Workers AI users

One of the most immediate benefits of this convergence is that you no longer need to explicitly create an AI Gateway before you start getting visibility into your inference traffic. If you've never set up a gateway before, just pass default as the gateway ID in your binding or REST API calls, and AI Gateway will create it automatically on the first authenticated request.

With this, every request is logged with full request and response payloads, token counts are tracked per model, and you get cost attribution without any dashboard setup. If you later outgrow the default gateway — if you want custom caching rules or to split traffic by application — you can create a named gateway and point your requests at it with a single parameter change.

Here's how it looks in the binding. Before, you called Workers AI directly:

Now, add a third argument to route through AI Gateway and get full observability:

Head to the Cloudflare AI Gateway dashboard and you'll see every request: latency breakdowns, token usage, error rates, and the exact prompts and responses. For teams debugging model behavior or auditing AI output, this is a huge upgrade from flying blind.

New: using AI Gateway credits for Workers AI

A new thing we're launching today is the ability to use AI Gateway credits for Workers AI. Before, you could only use AI Gateway credits on external model providers (e.g., OpenAI, Anthropic) but you couldn't apply your AI Gateway credits to Workers AI usage just yet. We've finally enabled our systems to allow unified billing for Workers AI. This means that you can load a wallet full of credits, and then choose to spend that across OpenAI, Anthropic, Workers AI, or any provider that we support.

Since we're now offering pre-paid billing for Workers AI and want to encourage users to use this new path, we're also offering elevated rate limits on Workers AI models if you use AI Gateway unified billing. Please refer to the developer docs for up-to-date information regarding rate limits, as well as how to request a higher rate limit.

Coming soon: model-first routing

With all your inference traffic flowing through a single control plane, we can start making smarter decisions about how to serve each request starting with the model you want, not the provider you have to manage. Provider-first routing forces you to think about infrastructure: "Which provider do I call? What if they're down?" Model-first routing flips that. You think about what you need — a capable reasoning model, a fast summarizer, a cheap embedding model — and the control plane handles provider selection, failover, and load balancing.

Today, if you want to call a model, you have to know which provider hosts it. If that provider is down or rate-limiting you, your application breaks. We're moving toward a world where you specify the model, and AI Gateway handles the rest. 

This way, you can request Kimi K2.7 Code and not care whether it comes from Workers AI, Moonshot's own API, or another provider that hosts the same weights. If Workers AI has capacity, you get the benefit of our managed infrastructure. If Workers AI is at capacity, the gateway transparently load balances you to another provider that can serve the same model. You can still choose to stick to a single provider if you’d like, but model-first routing enables you to get more flexibility if you care about resiliency. We work with vetted providers, so the quality of model outputs remains top priority, and will also be able to respect requirements such as Zero Data Retention (ZDR).

This also means better resiliency by default. If one provider's version of a model is having issues, traffic shifts to another without application-level retries or complex fallback logic in your Workers. The gateway treats model availability as a routing problem. We hope to pilot this in the coming months for all AI Gateway and Workers AI users.

Next: smart routing

The next evolution of routing goes beyond simple failover. We're building intelligent routing that understands what you're asking for and picks the right model for the job without any configuration required.

Instead of specifying a model, you can let the gateway decide. Under the hood, a classifier running on Workers AI reads your prompt and predicts what kind of task it is (coding, research, summarization, general Q&A), how complex it is, and how much context matters. A heuristic scorer then maps that to the best model from a curated pool. For teams that want control, you can still specify exact models. For everyone else, the zero-config path means you get better economics and performance without maintaining your own routing logic. We are currently piloting this internally, and we’ll be actively testing and iterating in the next few weeks before release. 

Get started today

If you're already using Workers AI, the easiest way to try this out is to start routing your existing calls through a default gateway. You'll immediately get request logging, token tracking, and cost attribution without changing anything else about how you call the models.

If you're already using AI Gateway, adding Workers AI to the mix is as simple as calling a Workers AI model. Load up your AI Gateway wallet and you'll get unified billing across every provider we support, plus elevated rate limits on Workers AI models.

Set up your first gateway, browse the Workers AI model catalog, and get started building today.

Introducing Radar Researcher: An AI tool for exploring Internet data in plain language

Post Syndicated from Lai Yi Ohlsen original https://blog.cloudflare.com/introducing-radar-researcher/

Since launching in 2020, Cloudflare Radar has provided one-of-a-kind insight into Internet traffic on a global scale. The open data that Radar publishes from our global network is used by a variety of experts in different domains: human rights advocates, journalists, academic researchers, network operators, and more.

Today, as part of Agents Week, Radar is beta-launching a new tool: Radar Researcher. 

Now, if you want to answer a question with Radar’s data, you can just ask in plain language and get an answer back with real, interactive charts, all built on Cloudflare's developer platform. You no longer need to find the right page, choose the right filters, or read the API documentation to write a query. 

Why we built Radar Researcher

Over the past six years, the Radar team has worked to provide clear, accessible, reliable data visualizations of complex datasets. This is not without its challenges: our user base is vast and ranges from curious novices to technical network experts. Even so, we publish as much insight into the Internet as seen from our network as we can: DNS queries from our public resolver 1.1.1.1, HTTP traffic from across our global network, network quality data collected from Cloudflare Speed Test, and so much more. We also believe in the power of open, public data, which is why everything you see in Radar’s data visualizations is available via our free API. Every year we make more and more of the Internet visible. 

But as Radar has evolved, so has the technology for working with data. AI tools are lowering the barrier to expertise: you no longer need to know a dataset's structure or vocabulary to get useful answers from it. Subject-matter experts become collaborators rather than gatekeepers.

Radar has always wanted to do more for users who shouldn't need to master our entire catalog and its vocabulary to fully appreciate our insights. (See our recent blog post on how the Internet responded to the 2026 FIFA World Cup.) 

We also know that many of our users are in a hurry. For example, a journalist writing about the latest Internet outage likely does not have the time to search through each page for the perfect graph to tell their story. This is why we built Radar Researcher.

Meet Radar Researcher

Radar Researcher is built to make accessing data as easy as describing what you’re looking for. All information is provided via Radar’s API, which ensures that the underlying LLM relies on real data, and can answer your questions quickly and in the same format as you would articulate them to a human.

It's available on every Radar page. Open the Radar Researcher panel from the header, and it docks beside whatever you're looking at, so you can keep browsing while you chat. Here are some examples of how you can use it: 

  • Get an answer in plain language, with real charts: Ask a question and get the same interactive visualizations you see across Radar, plus a short explanation.
  • Choose your depth: Pick a concise, direct answer or a fuller, multi-topic report.
  • Keep the analysis going: After each answer, it suggests useful follow-up questions.
  • Pick up where you left off: Conversations are saved in a searchable history you can pin and revisit, and you can share any conversation with a link. (Shared links expire automatically after 30 days.)
  • Audit the reasoning: Check how the LLM interpreted your question, which datasets it looked up and queried, and how it worked through the results to reach its answer.
  • Ask your way: Type, use voice input, or launch it straight from Radar's search bar.

Turn any chart into a conversation

Researcher doesn't only start from a blank prompt. Anywhere you see a chart on Radar, an Explain with AI action opens the assistant with that exact visualization already in hand. 

Instead of asking you to describe what you're looking at, it captures the exact visualization you're viewing and starts the conversation there. As you can see below, Radar Researcher takes the visualization in context, then analyzes the data and responds with an explanation.

Under the hood, the assistant hands the model three things at once: a screenshot of the chart (a vision-capable model reads the image directly), the exact data behind it from Radar's API, and the parameters of your current view, including location, date range, and any filters you've applied. The screenshot enables Radar Researcher to see what you see. The raw data keeps every number it cites precise instead of estimated from pixels, and the filters mean the explanation is about your exact view, not a generic version of the chart.

Use Case No. 1: What’s Internet quality like in Portugal?

Say you're curious how good the home Internet is in a given country. You can just ask:

Instead of manually calling the API, choosing parameters, or hunting through Radar's pages, Radar Researcher interprets the question and does the work for you. You can follow each step in the screenshot: it reads what you asked, queries Radar's Internet quality API, then analyzes the results and answers in plain language. And rather than a wall of numbers, it renders the same interactive charts you'd see on the Radar Internet Quality section.

From here you might ask a natural follow-up, like comparing Portugal to a neighbor, and Radar Researcher fetches fresh data for each one. It even suggests useful next steps of its own, such as how Portugal stacks up against Spain or the country's most common Internet outages. By letting you find what you're looking for in plain language, we hope applying Radar's data to your own analysis is easier than ever.

Use Case No. 2: Investigating an Internet disruption

Radar Researcher is also built with technical experts in mind. If we know one thing about engineers, researchers, and network operators, it’s that automation is key to their workflows. Looking at the same data with manual actions can be cumbersome and limiting: how do you ensure you're always looking at the most relevant data? 

Consider a real event. In early 2026, Iran went through a series of government-directed Internet shutdowns, including one that lasted nearly three months before traffic partially returned in May. Reporting a story like that means pulling several views and refreshing them as the situation develops. To investigate it, you can just ask Radar Researcher:

This time the question is open-ended, so Radar Researcher runs a short investigation. It looks up the outage events Cloudflare Radar recorded for Iran and gathers the matching traffic data, then explains the timeline in plain language: Iran's HTTP traffic index collapsed from around 0.58 on January 7 to effectively zero by January 9, began a partial recovery around January 17, and returned close to pre-shutdown levels by January 27. It presents this as an HTTP traffic index chart with the outage window annotated directly on the line, plus a table of the recorded outages that also flags a second shutdown starting February 28.

From there it suggests where to take the investigation next, such as how the traffic compared with neighboring countries.

How we built it

Radar Researcher is built entirely on Cloudflare's own developer platform. It's a showcase of the same tools any developer can use to build an AI agent.

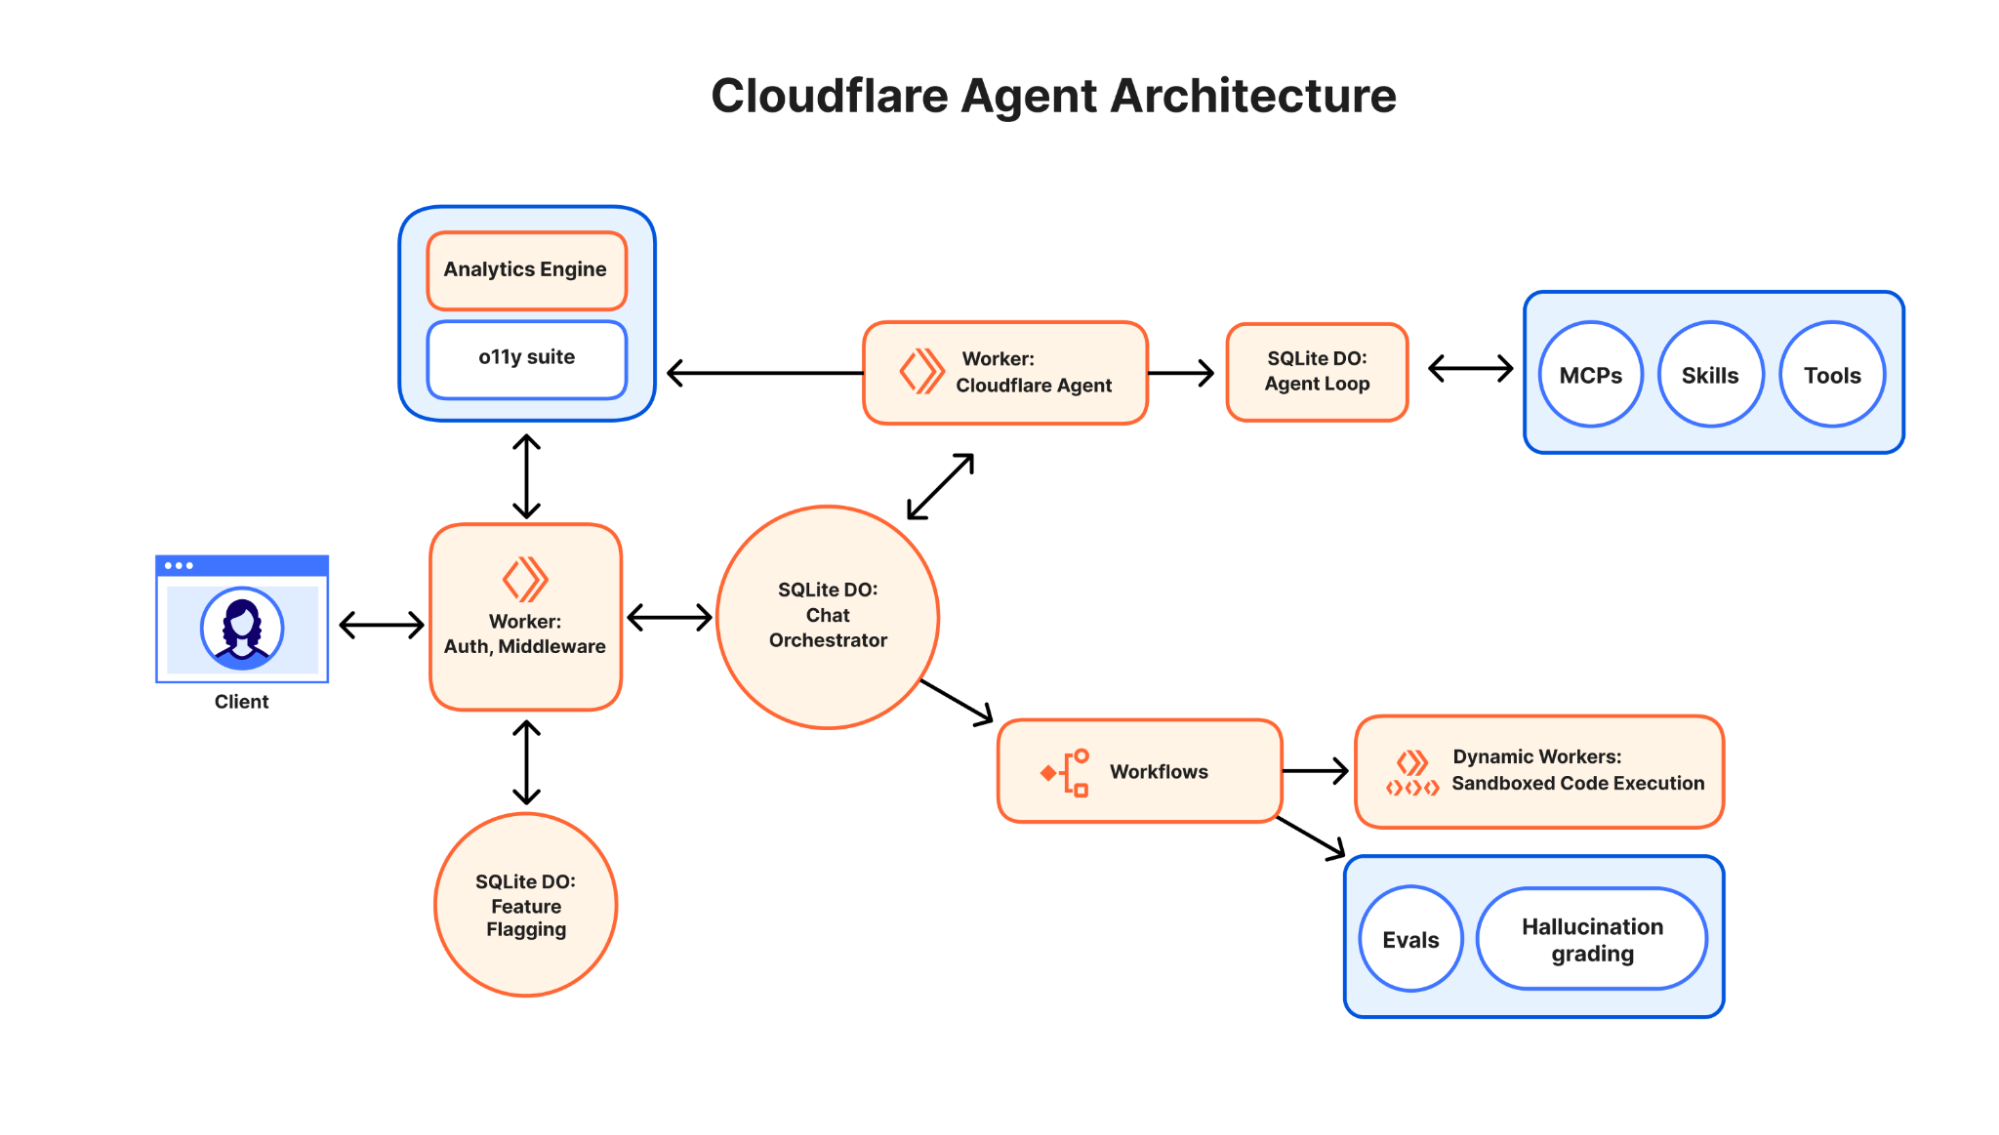
At its core is a Cloudflare Worker running the Cloudflare Agents SDK. Each conversation is a stateful Durable Object with its own SQLite database, so your chat history, titles, and streaming responses persist. They even survive you leaving the page mid-answer, because generation continues server-side and resumes when you reconnect.
The "brain" is Workers AI, running open models like Kimi K2.7. Rather than betting on a single model, we run an ordered fallback chain across three different model families. If one model is momentarily at capacity, the request transparently cascades to the next, so an incident at any single provider doesn’t take Researcher down. Every call routes through AI Gateway for logging, cost tracking, caching, and safety guardrails.

The most interesting part is how Researcher reaches Radar's data. Instead of hand-writing a tool for every one of Radar's hundreds of endpoints, we connect the agent to the unified Cloudflare MCP server using Code Mode. The model gets just three tools (search, execute, and docs) and writes code to query the Radar API directly. It searches the OpenAPI spec to find the right endpoint, then executes a small snippet that fetches live data. Because the full API spec lives on the MCP server, nothing about Radar's API is hard-coded into the prompt. As Radar adds datasets, Researcher can use them with no code changes.

This is visible to you, too: every answer includes an expandable trace of the model's reasoning and the exact tool calls it made to gather the data, so you can always see how it got there.

From Markdown to real Radar charts

There was one problem to solve along the way. Language models answer in Markdown: text, tables, and bullet points. But we didn't want walls of numbers; we wanted the same rich, interactive charts you see everywhere else on Radar. Worse, when a model tries to write data directly into its answer, it tends to round, summarize, or truncate it, which is exactly what you don't want from a data tool.

Our solution keeps the data out of the model's prose entirely. When Radar Researcher fetches data, its code returns a small envelope that pairs the API path with the result. Then, instead of pasting numbers, the model emits a lightweight chart specification that simply references that same path:

Radar's frontend matches the chart's dataFrom to the fetched result and renders it with the exact same visualization components used across the rest of the site. The chart is always faithful to the API, and Radar Researcher can draw on our whole visual vocabulary: time series and stacked areas, donuts, bar charts, maps, histograms, etc.

A few small touches

Not everything needs the big model. Small, fast models handle the side tasks: one writes a short title for each new conversation, and another suggests the follow-up questions under each answer. Both run off to the side, so they never slow down your actual reply.

Radar Researcher also gets a little context about the here and now. We pass it the current date and time, plus the same high-level details about your connection that you'll find on Radar's IP page, such as your IP location and network. That way, when you ask something like "how's traffic here?", it can tailor the answer to where you are.

Everything reaches you through Radar's frontend (also a Worker) over a service binding, with per-IP rate limiting and shareable conversations stored in R2. Every layer, from compute to inference to gateway to storage to data, is Cloudflare.

Powered by agents — and ready for them

Radar Researcher shows how we use an AI agent to help people explore our data. But there's another side to the agent story: what happens when the agent isn't ours, but a general-purpose assistant running in your browser, acting on your behalf?

Today, an agent that wants to use a website mostly has to scrape the page and guess at how it works, which is brittle, slow, and error-prone. WebMCP is an emerging web standard that fixes this: a page can register a small set of well-defined tools that any browser agent can discover and call directly, instead of reverse-engineering the DOM (Document Object Model).

We've added WebMCP support to Radar, using both flavors the standard offers:

  • The imperative API lets us register tools in JavaScript that call straight into the same code that powers the UI, so an agent can drive Radar directly. Filter to a country, region, continent, or ASN; change the date range; search pages, sections, and entities (domains, ASNs, IPs, and more); jump to any section.
  • The declarative API turns Radar's existing HTML forms into tools by annotating them with a couple of attributes, so an agent can scan a URL with the URL Scanner, look up a domain's report, or test a website's post-quantum TLS key exchange support.

Every one of these simply drives functionality already available in the user interface, and it's pure progressive enhancement: in a browser without WebMCP, the tools just aren't there and nothing changes.

It’s also a case of practicing what we preach. Radar’s own URL Scanner evaluates how agent-ready a site is, and one of those checks looks for exactly this kind of WebMCP integration. By implementing it ourselves, Radar now passes its own agent-readiness check, and, more importantly, becomes a site that both people and agents can navigate with ease.

Try it out 

Radar Researcher is available in beta today on Cloudflare Radar. Look for the Researcher button in the header on any page. It's built entirely on Cloudflare's developer platform, and it's just getting started: we'll keep expanding the datasets it understands, sharpening its analysis, and adding new ways to interact with data.

Like all Cloudflare products, Radar is built with the user in mind. We want to know what’s useful. Please let us know what you think on social media at @CloudflareRadar (X), noc.social/@cloudflareradar (Mastodon), and radar.cloudflare.com (Bluesky), or by email at [email protected]

Tell us what works, what doesn’t, the insights you’re finding, what still feels beyond reach, and everything in between. Your feedback will help us improve and make Radar Researcher even better for our full launch. We can’t wait to see what you do with it! 

How we built a software factory to drive Astro’s GitHub issue count to zero

Post Syndicated from Matthew Phillips original https://blog.cloudflare.com/astro-issue-triage/

Everyone is talking about software factories: the idea that AI agents can be assembled into a pipeline that produces working software on their own, the way a factory turns raw materials into finished goods. There’s endless debate over whether that’s actually possible, how far the automation can really go, and whether the “loops” people are demoing count for anything. Some have already written them off as a failure.

Running alongside that is a quieter, more worried conversation: open source maintainers are burning out. The AI boom has made it nearly free to generate issues, pull requests, and security reports, and enormously expensive for a maintainer to read through them all. The old ways of keeping a project healthy are buckling under the volume.

Everyone has a hot take on both topics. We think we have something rarer to offer: real results. For the past several months we’ve run an automated triage pipeline on the Astro repository. It reads incoming bug reports, reproduces them in sandboxes, diagnoses the root cause, and ships preview releases for the reporter to verify. The engine underneath it grew into Flue, an open framework for building this kind of agent automation, and it’s the same tool you could use to build your own.

It wasn’t an instant success. But through a lot of iteration, we’ve used it to bring our open issues down from over 200 to about 30, and we expect to hit zero sometime in the next month. That would be the first time this repository has seen zero open issues in its 5+ year history. 

We didn’t get there by declaring "issue bankruptcy," auto-closing cold tickets, or ignoring reports. We did it by automating issue triage with a team of isolated AI subagents running right inside GitHub Actions. Here’s the story of how we got there, and what you might take back to your own projects.

Starting with an agent skill

At the start of the year, we focused on automating one specific area of development: issue triage. As an open source project, manual issue triage can be one of the more time-consuming, least-rewarding parts of the job. A single issue can sometimes take hours just to reproduce, let alone fix. It was a natural (yet often overlooked) place for us to start our automation journey.

We began by developing an agent skill. This allowed us to develop and test the automation locally as maintainers, running a coding harness on our own machines. We could then run that same harness in a GitHub Action on our repo, and get total reuse of that exact same triage workflow skill.

The triage skill mirrors the exact steps we take during manual issue resolution:

  1. Reproduce: Clone the provided reproduction repository to verify the reported issue.
  2. Diagnose: Instrument the codebase and introduce logging to pinpoint the root cause of the bug.
  3. Verify: Review relevant test suites, code comments, and documentation to determine if the behavior is genuinely a bug or intended functionality.
  4. Fix: Convert the reproduction into failing unit tests, identify the appropriate solution via the architecture guide, and deploy the fix.

To prevent the frequent LLM bias toward forcing a solution when a bug might not actually exist, each phase is executed by an isolated subagent. These subagents pass information forward sequentially by compiling their discoveries into a report.md file.

Turning the skill into an automation

Following initial internal testing of the triage skill, our focus shifted toward building a fully automated pipeline. We specifically wanted to integrate this logic directly into a GitHub workflow, ensuring complete transparency so that anyone could easily audit the agent's sequential reasoning and operational steps.

As we wired it up, we realized the whole pipeline was really just a state machine driven by issue labels. Every new submission starts with the label triage needed, and once a user confirms a fix it moves to fix verified. Beyond those label transitions the pipeline holds no state of its own; it simply reads back through the issue’s existing comments to work out where a given issue is and what should happen next.

From there the flow runs on its own. When the agents land on a fix, the pipeline spins up a preview release with pkg.pr.new and posts everything back to the issue: a summary of what it found, the full logs, and instructions for installing the preview. The original reporter can then try the patch against their own project, and if they confirm it works, the automation opens a pull request linked to the issue.

From triage to a framework

As we built this out, we kept noticing that nothing about it was really specific to GitHub. Reacting to an event, running a sequence of isolated subagents, and separating their reasoning from the actions they’re allowed to take — it’s all just a workflow. One that could run just as well from a Slack message, a cron job, or a webhook as from a GitHub issue. Generalizing that realization into a runtime that works the same way regardless of where it’s deployed, or which model it’s driving, is what became Flue: an open, platform-agnostic framework for building durable agents and workflows.

Benefits of agent automation

When we first launched this automated system, we had shared concerns about its efficacy and the potential negative impacts it might have on our developer community. There was a valid fear that relying on automated bot responses might feel impersonal and create just one more disconnect between us as maintainers and our user base.

That did not happen. If anything, we talk to users more now, just in more useful places:

  • Engaging directly with our community members within Discord.
  • Actively participating in RFC discussions and addressing new feature requests.
  • Collaborating closely with contributors to help integrate their ideas into the framework.

Regarding the quality of automated patches, our core philosophy is that our AI agents should successfully resolve the vast majority of incoming issues. When an agent fails to identify a correct solution, we interpret that failure as an indicator of an underlying architectural or documentation issue within the codebase, pointing to one of three areas:

  • Opaque Abstractions: If an agent cannot interpret the boundaries between components, human developers likely struggle with the code structure as well.
  • Missing Documentation: Critical code segments lack explicit comments explaining the rationale behind their implementation.
  • Insufficient Testing: The repository suffers from a lack of comprehensive test coverage, particularly unit tests.

A clear example occurred with a series of related Hot Module Replacement (HMR) bugs. The triage bot repeatedly attempted to modify a specific if condition to resolve the issue. While this change fixed the targeted bug, it introduced regressions elsewhere due to a lack of test coverage for that specific condition. Once we added a descriptive comment explaining the exact logic governing that statement, the bot adapted and stopped attempting incorrect modifications in that area.

Every time we chase down one of these failures and add the missing comment, test, or clearer boundary, the bot gets noticeably better at that part of the codebase, and so does the next human who works on it.

Turning the workflow into a GitHub Action

Initially, our triage logic lived directly within the Astro monorepo. This coupling made iteration difficult; upgrading Flue or modifying the workflow felt like performing surgery on live infrastructure without a safety net. To solve this, we decoupled the logic into a standalone, testable repository: triagebot-action. This isolation allowed us to introduce automated testing and ensure stability before ever touching our primary codebase.

Today, this action powers issue management in Astro, and it has spread from there. Several other teams have picked it up, some using it directly, and others forking it to build their own automated "factories" tailored to their projects. That second path is really the point: triagebot-action is young and still actively evolving, so we’re sharing it less as a finished product and more as a working reference you can read, learn from, and adapt. 

The wiring for the action itself looks like this:

Or point your own agent at the repository and have it read through the setup, including adding the labels the state machine relies on.

Whichever route you take, the underlying idea matters more than our specific implementation: a sustainable feedback loop that frees maintainers to focus on the framework itself instead of administering a backlog. The code is open. Fork it, strip it down, or just borrow the parts that fit your project.

Want to build something like this? Dig into the code of the triagebot-action to see how it works, or fork it as a starting point for your own repository’s automation. And if you’re building agent-based infrastructure more seriously, that’s exactly what Flue is for: dive into the Flue framework to build your own. We’d love to see what you build. Come share your "factory" stories in the Astro Discord.

Smaller, faster, safer: running Kimi and GLM at scale

Post Syndicated from Alex Reneau original https://blog.cloudflare.com/smaller-faster-safer-models/

Workers AI runs inference for some of the best open models in the world on GPUs in Cloudflare data centers close to your users. Two of the most capable, and most demanding, are Moonshot's Kimi K-series and Z.ai's GLM. They are large, long-context, mixture-of-experts models, and they are wonderful to use. They are also very hard to serve efficiently because of memory constraints.

We've written before about how we serve large models on Workers AI and about separating the prefill and decode phases of inference to get more out of each GPU. This post looks at three techniques we layer on top of that to fit these models into memory and keep them fast: quantizing the KV cache, compressing the model weights, and, because both of those pack more requests onto shared hardware, protecting the cache those requests share. These optimizations enable us to support more customers at lower costs, with no change in model accuracy.

All our experiments and production traffic are running and benchmarked with SGLang, an open-source inference serving framework. We found that SGLang offers the best performance in the market, and we work closely with the SGLang team to upstream patches and new features to make our work available to the open-source community.

Quantizing the KV cache

As a model generates text, it stores the attention keys (K) and values (V) for every token it has already processed in a structure called the KV cache. The cache is what lets the model extend a long conversation without re-reading the entire context on every new token. For a long-context model, it grows quickly, and it is usually the KV cache, not the model's weights, that fills up GPU memory first.

By default, the cache is stored in 16-bit precision (BF16). We store it in 8-bit floating point instead (FP8, e4m3), which halves its size. On Kimi K2.6, that raises the amount of context we can hold in memory from roughly 686,000 tokens to about 1.37 million, twice as much.

It's worth being precise about where the benefit comes from, because it isn't raw speed. Quantizing the cache adds a small amount of work per token, since the FP8 attention kernel has to convert values as it reads them. What it changes is how many requests we can keep resident at once. The following measurements are for Kimi K2.6 decoding on a disaggregated H200 deployment, comparing the attention kernels directly:

At any single concurrency level, BF16 is a few percent faster per token. But BF16 runs out of cache at 32 concurrent requests and can't admit a 33rd, while FP8 keeps going to 64 and reaches 2,192 tokens per second, about 41% higher than BF16's peak, for roughly 30% less cost per token. Because we run prefill and decode as separate pools, we can apply this where it helps most: prefill is compute-bound rather than memory-bound, so there we leave the cache in BF16 and keep its slightly higher throughput.

None of this would matter if it changed the model's answers, so we checked. Across our evaluation suite, FP8 and BF16 caches are indistinguishable:

Compressing the model weights

The KV cache is one demand on GPU memory; the model's weights are the other. For GLM 5.2, we compress the weights from 8-bit floating point down to 4-bit integers (INT4) with no loss in accuracy. The checkpoint shrinks from 705 GB to 421 GB, about 40%, and per-GPU memory across an 8-way tensor-parallel deployment drops from roughly 88 GB to 52 GB, which leaves room for around 1.18 million tokens of KV cache on the same hardware.

Across our evaluation suite, INT4 and FP8 weights are indistinguishable:

Smaller weights make the decode phase faster, and for a clear reason: generating each token means streaming the model's weights out of GPU memory, so decode speed is limited by memory bandwidth. Move less data and every token arrives sooner. The effect is largest at low concurrency, where per-request latency matters most:

Prefill behaves differently. It is compute-bound, and INT4 weights have to be expanded back out before the model can multiply with them, so that extra step makes prefill slower rather than faster, GLM sustains about 10,160 tokens per second of prefill in FP8 versus 8,660 in INT4. As with the KV cache, the disaggregated design turns this into a choice rather than a compromise: we run INT4 for decode, where it wins, and FP8 for prefill, where it wins. Model accuracy stays within 0.8 points of the FP8 model across every benchmark we run, making its quality indistinguishable.

Protecting a shared KV cache

Both techniques above have the same effect: they let many more requests share one GPU's memory at the same time. That efficiency is the whole point, but it also means hundreds of requests are reading and writing pages of the same physical KV cache. The mechanisms that make this fast, paged attention, continuous batching, cache reuse, all rely on getting the bookkeeping exactly right, and at our request volumes, even a one-in-a-billion mistake would show up regularly.

So we built KV cache integrity checking as a layer of defense. The idea is straightforward: every physical cache page gets a tag that changes whenever the page is reallocated, and the server records which pages and tags each request expects to use. Before supported decode operations read from the cache, those mappings are checked. If anything doesn't match, the affected request is aborted rather than allowed to return data from the wrong page.

The question that decides whether a safety check ships is what it costs. We measured it on a mid-sized production model in a two-prefill, two-decode configuration, with 8,192-token inputs and 1,000-token outputs:

The cost is under 1% on both throughput and tail latency, and even the upper bound of the 95% confidence interval stays near 1%. We kept it computationally cheap by running the validation as a separate batch check rather than fusing it into the attention kernel, which would have introduced a race between GPU thread groups. It's enabled per deployment, and the default path uses a no-op tracker with no measurable overhead, so deployments that don't need it pay nothing.

What's next

Serving frontier models efficiently is a moving target, and this is the ongoing work behind it. We're expanding FP8 KV caches across more of the fleet, validating NVFP4 weights on Blackwell (NVIDIA’s GPU architecture), and working toward making integrity checks something we can leave on everywhere at negligible cost. These optimizations will allow us to continue to support more customers at a lower cost and at the same accuracy.

If squeezing the best open models onto GPUs and serving them to millions of developers sounds like your kind of problem, come work with us.

Growing the Cloudflare AI team with talent from Ensemble AI

Post Syndicated from Alex Reneau original https://blog.cloudflare.com/ensemble-ai-talent-joins-cloudflare/

Today, we’re excited to share that key members of the team at Ensemble AI are joining Cloudflare to help accelerate our work in AI infrastructure and make it easier for developers to run powerful AI models efficiently at scale.

Ensemble AI, founded in 2023 in San Francisco, has spent the last few years focused on one of the most important challenges in AI: making large models faster, smaller, and more cost-effective to serve, without sacrificing quality. The team has developed new approaches to model compression and efficient inference that are designed to reduce the memory, compute, and deployment overhead of large language models and multimodal architectures.

As AI becomes a core part of how developers build applications, the economics of inference matter more than ever. Models are getting larger; workloads are becoming more dynamic. And customers increasingly expect AI to be available everywhere: globally distributed, fast, reliable, and affordable. Bringing the Ensemble AI team into Cloudflare strengthens our ability to make that possible.

Incorporating Ensemble’s expertise 

The team at Ensemble AI has focused on preserving the structure inside modern AI models while reducing the cost of running them. Instead of treating model efficiency as only a quantization or hardware problem, Ensemble has explored new model building blocks that can make neural networks more compact and efficient at the architectural level.

A core part of this work is NdLinear, a drop-in replacement for standard linear layers in transformer models that operates directly on multidimensional activations rather than flattening structure away. This enables models to preserve meaningful axes, such as heads, channels, spatial dimensions, or other structured representations, while reducing parameter count and compute. Ensemble has also developed NdLinear-LoRA, an efficient adaptation method designed to reduce the trainable parameters required for fine-tuning large models.

These approaches complement other efficiency techniques, including quantization and vector quantization. Together, they point toward a future where developers can run capable AI models with substantially lower memory, compute, and cost requirements.

Making AI inference more efficient

Cloudflare Workers AI gives developers access to serverless GPU-powered inference on Cloudflare’s global network. As developers build more AI-native applications, the ability to serve models efficiently becomes a critical part of the platform.

Inference cost is one of the biggest barriers to scaling AI applications. Every improvement in model size, memory footprint, throughput, and GPU utilization can make AI more accessible to developers and more economical for customers. This is especially important as AI workloads expand beyond simple text generation into agents, multimodal models, personalization, fine-tuning, retrieval, and reinforcement learning.

We are deepening our investment in the core machine learning capabilities needed to make Workers AI faster, more flexible, and more cost-efficient. This builds on top of our existing work on improving model efficiency, including our inference engine Infire, tensor compression techniques like Unweight, and our platform for running extra large language models. The team will focus on improving the economics of serving large language models and other advanced AI architectures, with an emphasis on model efficiency, GPU utilization, and scalable deployment.

Building for the next generation of AI workloads

AI infrastructure is entering a new phase. Developers no longer need only access to models; they need infrastructure that can run models reliably, affordably, and close to users. They need the ability to experiment with different model sizes, fine-tuning approaches, and deployment patterns without being blocked by cost or operational complexity.

Cloudflare is uniquely positioned to help solve this. Our global network, developer platform, and serverless architecture give us the foundation to bring AI closer to where applications already run. The Workers AI Machine Learning Engineering team will help us improve the efficiency layer underneath that experience.

By combining Cloudflare’s global infrastructure with Ensemble’s work in model compression and efficient architectures, we can continue building a platform where developers can deploy AI applications with lower cost, better performance, and less operational overhead.

What’s next

Together, we will continue building the infrastructure needed to make AI more efficient, accessible, and useful for developers everywhere. Our goal is simple: help developers run powerful AI workloads at global scale while improving the economics of inference across the Cloudflare platform. If you want to join us in our mission, check out our careers page.


VoidZero is joining Cloudflare

Post Syndicated from Evan You original https://blog.cloudflare.com/voidzero-joins-cloudflare/

VoidZero, the company behind Vite, Vitest, Rolldown, Oxc, and Vite+, is joining Cloudflare. As part of this change, all team members of VoidZero are joining Cloudflare, too.

Before saying anything else, we want to make the most important thing clear: Vite, Vitest, Rolldown, Oxc, and Vite+ will stay open source, vendor-agnostic, and community-driven. Nothing about that changes.

Cloudflare’s mission is to help build a better Internet. And a better Internet is an open Internet. Developers need choice, frameworks need a neutral foundation, and applications need to be portable. It is not reasonable to expect the entire web ecosystem to build around a single vendor. The most important tools and frameworks are portable by design.

Vite is one of the few foundational tools that the whole JavaScript ecosystem agrees on. It earned that position by being fast, excellent, portable, and vendor-neutral. One of the best ways Cloudflare can help build a better Internet is by investing in that foundational open source toolchain. A toolchain that makes the Internet better for everyone, not just people who use Cloudflare or choose to host with us.

Over the last few years we’ve invested heavily in making Cloudflare the best place to build and run websites, applications, and agents on our developer platform. But ultimately that choice will always be yours. Run your Vite application anywhere you want.

What this means for Vite

Today’s news gives Vite more resources to keep growing, while the things that make Vite what it is remain the same:

  • Vite remains MIT-licensed and open source.

  • Vite remains vendor-agnostic. Applications built with Vite run anywhere and will continue to do so.

  • Vite’s roadmap continues to be driven by the broader Vite team and community, and continues to be developed in the open.

  • Evan and the rest of the VoidZero team continue to lead Vite, Vitest, Rolldown, Oxc, and Vite+.

  • Cloudflare is committing engineering and resources to those projects, not redirecting them.

We made the same kind of commitment when Astro joined Cloudflare earlier this year. Astro is still open source, and still deploys anywhere. The team is still shipping the roadmap they were already shipping.

This commitment matters even more with Vite, because Vite is not one framework. Vite is the foundation underlying so many: Vue, SvelteKit, Nuxt, Astro, Solid, Qwik, Angular, React Router, TanStack Start. Even Next.js now has a Vite-based implementation in vinext. Vite has become a shared substrate for the JavaScript ecosystem. 

Our number one goal is to maintain the trust that has earned Vite so much adoption. Not with our words here, but by proving it every day in how we support and develop these projects.

We also want to put our money where our mouth is when it comes to our support for open source and shared ecosystem foundations. As part of this announcement, Cloudflare is committing $1 million to a Vite ecosystem fund to support maintainers and contributors, administered by the Vite core team. Vite is bigger than VoidZero or Cloudflare, and the people who have helped build it should be part of what comes next.

Vite as the foundation

The Vite and Cloudflare teams have been collaborating well before this announcement, starting in 2024 with the Vite Environment API. The Environment API lets Vite run server code in something other than Node.js during development. We worked closely with the Vite team on its design, and then built the Cloudflare Vite plugin on top of it.

When you run vite dev with the Cloudflare plugin, your server code runs inside workerd, the same open-source runtime that powers Workers in production. Durable Objects, D1, KV, R2, Workflows, Workers AI, Agents, Service Bindings, Workers RPC – all of it runs locally inside the same runtime model as production.

For a long time, the cost of developing on a non-Node runtime was that local dev felt like a worse version of production. The Environment API removed that cost without forcing anyone to adopt a Cloudflare-specific dev server. Any runtime that wants to plug into Vite can do the same thing. That kind of design – a generic mechanism in Vite with provider-specific implementations – has proven to work well and is one we want to keep building on.

We knew we were on to something when we saw adoption of the Cloudflare Vite plugin take off:


Vite’s adoption curve is one of the more remarkable things to watch in the ecosystem right now. As of this writing, Vite is at roughly 129M weekly downloads. The Cloudflare Vite plugin (@cloudflare/vite-plugin) is at almost 14M weekly downloads.

If you had told us a year ago that a Cloudflare Vite plugin would reach downloads equivalent to more than 10% of Vite itself, we wouldn’t have believed you. What happened? AI happened. More software is being created than ever before, and a lot of it starts with AI-generated code. Those applications need a default stack and a place to run. Agent-coded applications are choosing Vite, and increasingly they are choosing Vite running on Cloudflare.

AI is changing how we write software

Developers used to be the only users of dev servers, bundlers, linters, formatters, and CLIs. That is no longer true: agents are using them too, constantly. They scaffold projects, run dev servers, read errors, write tests, lint and format code, deploy previews, and iterate.

A lot of AI-generated applications already start as Vite apps, because Vite is fast, well understood, and broadly compatible with what agents have seen in their training data. Fast feedback loops have always been important. They become even more critical when writing software with agents:

  • Fast builds, because they iterate more than humans do.

  • Fast tests, because they re-run the suite constantly to verify their own work.

  • Fast linting and formatting, because those tools become guardrails.

  • Clear, structured errors, because the agent has to read and act on them.

  • Consistent CLIs, because small inconsistencies cause big detours.

The entire VoidZero toolchain is built for this kind of loop. Vitest, Rolldown, Oxc, Oxlint, and Oxfmt are each among the fastest tools in their respective categories, and they work well when they are run over and over by an agent. Vite+ brings those pieces together into one toolchain, with one CLI, one configuration model, and fewer moving parts. That makes the development loop easier for people to understand, and easier for agents to drive reliably.

We are dogfooding this ourselves. The Cloudflare dashboard is built on Vite. Oxlint is already saving days of engineering time in Cloudflare codebases. Flue, the agent harness framework from the Astro team, is also moving onto Vite as its foundation. Flue can run agents on Node.js, Cloudflare Workers, GitHub Actions, GitLab CI/CD, and more, and the Cloudflare target now uses the official Cloudflare Vite plugin and workerd integration. Vite is becoming the default application foundation inside Cloudflare too.

Vite is becoming full-stack

A few years ago, the job of a build tool was straightforward: take source files, produce a bundle, hand it off. That is not enough for modern applications, especially in a world where some of those applications are agents themselves.

A modern application is server-rendered routes, APIs, background jobs, queues, databases, object storage, real-time, auth, plus a growing list of agents and AI capabilities. The “build” is no longer the end of the story. It is the start of a deployment that has to understand all of those pieces.

That means Vite has to become more than a build tool. It needs to understand more of the application, while staying true to what made Vite work in the first place: speed, simplicity, and portability.

Void, a deployment platform designed for Vite, has been another testbed for these ideas. It helped explore what a modern application framework should own, what deployment should feel like, and how much of the full application lifecycle can be unified around one toolchain. We have learned a lot from that work.

Now the work is putting those lessons in the right place. Some belong in Vite itself as provider-agnostic primitives: first-class abstractions and hooks for backends, APIs, agents, and deployment that any provider can implement. Other lessons belong inside Cloudflare. Cloudflare will provide a first-class implementation of those hooks on Workers and the rest of our Developer Platform.

Even though some Vite maintainers are joining Cloudflare, changes to Vite itself will continue to go through the same open contribution process as any other Vite contribution. Features added to Vite itself should not be Cloudflare-specific. They will work anywhere Vite works.

Moving Cloudflare toward Vite

The same principle shaped how we think about the future of Cloudflare’s own tooling. We are not moving Vite in the direction of Cloudflare. We are doing the opposite: moving Cloudflare’s application tooling onto Vite, so it is built on top of the same workflows developers already know.

We recently shipped a technical preview of cf, a new unified CLI for the whole Cloudflare platform. Vite is going to be the foundation of our CLI experience for applications. The end goal is one consistent CLI for all of Cloudflare, with the same ergonomics whether you are working on Workers, R2, D1, Agents, or anything else.

If we do this right, the Cloudflare CLI should feel like Vite, not like a separate thing bolted on next to Vite.

  • cf dev should be a superset of vite dev. Same speed, same hot module replacement, same plugin model, plus the Cloudflare runtime and bindings when you want them.

  • cf build should understand Vite projects natively, without an adapter dance.

  • cf deploy should make deploying a Vite app to Cloudflare simple.

If you are running Vite today, the path to Cloudflare will feel like swapping in a superset of the commands you already know. Same project shape. Same Vite workflows. The entire Cloudflare developer platform available when you want it.

What happens next

In the short term, nothing changes for Vite users or the frameworks building on top of Vite:

  • Vite, Vitest, Rolldown, Oxc, and Vite+ keep shipping. The VoidZero team keeps contributing and leading them.

  • The Cloudflare Vite plugin keeps improving.

  • The Environment API and the broader story of “run your server code in the right runtime locally” keeps getting better, including for non-Cloudflare runtimes.

Longer term:

  • We start the work on moving the Cloudflare CLI toward an experience built directly on top of Vite.

  • Vite will get new, clean, provider-agnostic primitives for full-stack apps and agents that work for everyone on any platform.

  • Over time, we intend to open-source the Void platform, so others can learn from it and build their own platforms on top of Vite and Cloudflare.

We will do all of this in public and with the community. The same way Vite has always been built.

Welcome VoidZero

Vite, Vitest, Rolldown, Oxc, and Vite+ exist because a deep ecosystem of open source contributors put years of work into them. These projects are already foundational to how the web is built, and we are grateful to everyone who helped get them here. Thank you to everyone who has contributed code, reviews, issues, docs, plugins, integrations, and support along the way.

We are excited to welcome the VoidZero team to Cloudflare, and excited to put more resources behind these projects. Our job now is to help them grow, stay open, and power the JavaScript ecosystem for everyone.

Vite keeps being Vite. Cloudflare gets to help.

If you want to try Vite on Cloudflare today, run:

  • npm create vite@latest

  • npx wrangler deploy

The AI engineering stack we built internally — on the platform we ship

Post Syndicated from Ayush Thakur original https://blog.cloudflare.com/internal-ai-engineering-stack/

In the last 30 days, 93% of Cloudflare’s R&D organization used AI coding tools powered by infrastructure we built on our own platform.

Eleven months ago, we undertook a major project: to truly integrate AI into our engineering stack. We needed to build the internal MCP servers, access layer, and AI tooling necessary for agents to be useful at Cloudflare. We pulled together engineers from across the company to form a tiger team called iMARS (Internal MCP Agent/Server Rollout Squad). The sustained work landed with the Dev Productivity team, who also own much of our internal tooling including CI/CD, build systems, and automation.

Here are some numbers that capture our own agentic AI use over the last 30 days:

  • 3,683 internal users actively using AI coding tools (60% company-wide, 93% across R&D), out of approximately 6,100 total employees

  • 47.95 million AI requests 

  • 295 teams are currently utilizing agentic AI tools and coding assistants.

  • 20.18 million AI Gateway requests per month

  • 241.37 billion tokens routed through AI Gateway

  • 51.83 billion tokens processed on Workers AI

The impact on developer velocity internally is clear: we’ve never seen a quarter-to-quarter increase in merge requests to this degree.


As AI tooling adoption has grown the 4-week rolling average has climbed from ~5,600/week to over 8,700. The week of March 23 hit 10,952, nearly double the Q4 baseline.

MCP servers were the starting point, but the team quickly realized we needed to go further: rethink how standards are codified, how code gets reviewed, how engineers onboard, and how changes propagate across thousands of repos.

This post dives deep into what that looked like over the past eleven months and where we ended up. We’re publishing now, to close out Agents Week, because the AI engineering stack we built internally runs on the same products we’re shipping and enhancing this week.

The architecture at a glance

The engineer-facing tools layer (OpenCode, Windsurf, and other MCP-compatible clients) include both open-source and third-party coding assistant tools.


Each layer maps to a Cloudflare product or tool we use:

What we built

Built with

Zero Trust authentication

Cloudflare Access

Centralized LLM routing, cost tracking, BYOK, and Zero Data Retention controls

AI Gateway

On-platform inference with open-weight models

Workers AI

MCP Server Portal with single OAuth

Workers + Access

AI Code Reviewer CI integration

Workers + AI Gateway

Sandboxed execution for agent-generated code (Code Mode)

Dynamic Workers

Stateful, long-running agent sessions

Agents SDK (McpAgent, Durable Objects)

Isolated environments for cloning, building, and testing

Sandbox SDK — GA as of Agents Week

Durable multi-step workflows

Workflows — scaled 10x during Agents Week

16K+ entity knowledge graph

Backstage (OSS)

None of this is internal-only infrastructure. Everything (besides Backstage) listed above is a shipping product, and many of them got substantial updates during Agents Week.

We’ll walk through this in three acts:

  1. The platform layer — how authentication, routing, and inference work (AI Gateway, Workers AI, MCP Portal, Code Mode)

  2. The knowledge layer — how agents understand our systems (Backstage, AGENTS.md)

  3. The enforcement layer — how we keep quality high at scale (AI Code Reviewer, Engineering Codex)

Act 1: The platform layer

How AI Gateway helped us stay secure and improve the developer experience

When you have over 3,600+ internal users using AI coding tools daily, you need to solve for access and visibility across many clients, use cases, and roles.

Everything starts with Cloudflare Access, which handles all authentication and zero-trust policy enforcement. Once authenticated, every LLM request routes through AI Gateway. This gives us a single place to manage provider keys, cost tracking, and data retention policies.


The OpenCode AI Gateway overview: 688.46k requests per day, 10.57B tokens per day, routing to four providers through one endpoint.

AI Gateway analytics show how monthly usage is distributed across model providers. Over the last month, internal request volume broke down as follows.

Provider

Requests/month

Share

Frontier Labs (OpenAI, Anthropic, Google)

13.38M

91.16%

Workers AI

1.3M

8.84%

Frontier models handle the bulk of complex agentic coding work for now, but Workers AI is already a significant part of the mix and handles an increasing share of our agentic engineering workloads.

How we increasingly leverage Workers AI

Workers AI is Cloudflare’s serverless AI inference platform which runs open-source models on GPUs across our global network. Beyond huge cost improvements compared to frontier models, a key advantage is that inference stays on the same network as your Workers, Durable Objects, and storage. No cross-cloud hops to deal with, which cause more latency, network flakiness, and additional networking configuration to manage.


Workers AI usage in the last month: 51.47B input tokens, 361.12M output tokens.

Kimi K2.5, launched on Workers AI in March 2026, is a frontier-scale open-source model with a 256k context window, tool calling, and structured outputs. As we described in our Kimi K2.5 launch post, we have a security agent that processes over 7 billion tokens per day on Kimi. That would cost an estimated $2.4M per year on a mid-tier proprietary model. But on Workers AI, it’s 77% cheaper.

Beyond security, we use Workers AI for documentation review in our CI pipeline, for generating AGENTS.md context files across thousands of repositories, and for lightweight inference tasks where same-network latency matters more than peak model capability.

As open-source models continue to improve, we expect Workers AI to handle a growing share of our internal workloads. 

One thing we got right early: routing through a single proxy Worker from day one. We could have had clients connect directly to AI Gateway, which would have been simpler to set up initially. But centralizing through a Worker meant we could add per-user attribution, model catalog management, and permission enforcement later without touching any client configs. Every feature described in the bootstrap section below exists because we had that single choke point. The proxy pattern gives you a control plane that direct connections don’t, and if we plug in additional coding assistant tools later, the same Worker and discovery endpoint will handle them.

How it works: one URL to configure everything

The entire setup starts with one command:

opencode auth login https://opencode.internal.domain

That command triggers a chain that configures providers, models, MCP servers, agents, commands, and permissions, without the user touching a config file.


Step 1: Discover auth requirements. OpenCode fetches config from a URL like https://opencode.internal.domain/.well-known/opencode

This discovery endpoint is served by a Worker and the response has an auth block telling OpenCode how to authenticate, along with a config block with providers, MCP servers, agents, commands, and default permissions:

{
  "auth": {
    "command": ["cloudflared", "access", "login", "..."],
    "env": "TOKEN"
  },
  "config": {
    "provider": { "..." },
    "mcp": { "..." },
    "agent": { "..." },
    "command": { "..." },
    "permission": { "..." }
  }
}

Step 2: Authenticate via Cloudflare Access. OpenCode runs the auth command and the user authenticates through the same SSO they use for everything else at Cloudflare. cloudflared returns a signed JWT. OpenCode stores it locally and automatically attaches it to every subsequent provider request.

Step 3: Config is merged into OpenCode. The config provided is shared defaults for the entire organization, but local configs always take priority. Users can override the default model, add their own agents, or adjust project and user scoped permissions without affecting anyone else.

Inside the proxy Worker. The Worker is a simple Hono app that does three things:

  1. Serves the shared config. The config is compiled at deploy time from structured source files and contains placeholder values like {baseURL} for the Worker’s origin. At request time, the Worker replaces these, so all provider requests route through the Worker rather than directly to model providers. Each provider gets a path prefix (/anthropic, /openai, /google-ai-studio/v1beta, /compat for Workers AI) that the Worker forwards to the corresponding AI Gateway route.

  2. Proxies requests to AI Gateway. When OpenCode sends a request like POST /anthropic/v1/messages, the Worker validates the Cloudflare Access JWT, then rewrites headers before forwarding:

    Stripped:   authorization, cf-access-token, host
    Added:      cf-aig-authorization: Bearer <API_KEY>
                cf-aig-metadata: {"userId": "<anonymous-uuid>"}
    

    The request goes to AI Gateway, which routes it to the appropriate provider. The response passes straight through with zero buffering. The apiKey field in the client config is empty because the Worker injects the real key server-side. No API keys exist on user machines.

  3. Keeps the model catalog fresh. An hourly cron trigger fetches the current OpenAI model list from models.dev, caches it in Workers KV, and injects store: false on every model for Zero Data Retention. New models get ZDR automatically without a config redeploy.

Anonymous user tracking. After JWT validation, the Worker maps the user’s email to a UUID using D1 for persistent storage and KV as a read cache. AI Gateway only ever sees the anonymous UUID in cf-aig-metadata, never the email. This gives us per-user cost tracking and usage analytics without exposing identities to model providers or Gateway logs.

Config-as-code. Agents and commands are authored as markdown files with YAML frontmatter. A build script compiles them into a single JSON config validated against the OpenCode JSON schema. Every new session picks up the latest version automatically.

The overall architecture is simple and easy for anyone to deploy with our developer platform: a proxy Worker, Cloudflare Access, AI Gateway, and a client-accessible discovery endpoint that configures everything automatically. Users run one command and they’re done. There’s nothing for them to configure manually, no API keys on laptops or MCP server connections to manually set up. Making changes to our agentic tools and updating what 3,000+ people get in their coding environment is just a wrangler deploy away.

The MCP Server Portal: one OAuth, multiple MCP tools

We described our full approach to governing MCP at enterprise scale in a separate post, including how we use MCP Server Portals, Cloudflare Access, and Code Mode together. Here’s the short version of what we built internally.


Our internal portal aggregates 13 production MCP servers exposing 182+ tools across Backstage, GitLab, Jira, Sentry, Elasticsearch, Prometheus, Google Workspace, our internal Release Manager, and more. This unifies access and simplifies everything giving us one endpoint and one Cloudflare Access flow governing access to every tool.

Each MCP server is built on the same foundation: McpAgent from the Agents SDK, workers-oauth-provider for OAuth, and Cloudflare Access for identity. The whole thing lives in a single monorepo with shared auth infrastructure, Bazel builds, CI/CD pipelines, and catalog-info.yaml for Backstage registration. Adding a new server is mostly copying an existing one and changing the API it wraps. For more on how this works and the security architecture behind it, see our enterprise MCP reference architecture.

Code Mode at the portal layer

MCP is the right protocol for connecting AI agents to tools, but it has a practical problem: every tool definition consumes context window tokens before the model even starts working. As the number of MCP servers and tools grows, so does the token overhead, and at scale, this becomes a real cost. Code Mode is the emerging fix: instead of loading every tool schema up front, the model discovers and calls tools through code.

Our GitLab MCP server originally exposed 34 individual tools (get_merge_request, list_pipelines, get_file_content, and so on). Those 34 tool schemas consumed roughly 15,000 tokens of context window per request. On a 200K context window, that’s 7.5% of the budget gone before asking a question. Multiplied across every request, every engineer, every day, it adds up.

MCP Server Portals now support Code Mode proxying, which lets us solve that problem centrally instead of one server at a time. Rather than exposing every upstream tool definition to the client, the portal collapses them into two portal-level tools: portal_codemode_search and portal_codemode_execute.


The nice thing about doing this at the portal layer is that it scales cleanly. Without Code Mode, every new MCP server adds more schema overhead to every request. With portal-level Code Mode, the client still only sees two tools even as we connect more servers behind the portal. That means less context bloat, lower token cost, and a cleaner architecture overall.

Act 2: The knowledge layer

Backstage: the knowledge graph underneath all of it

Before the iMARS team could build MCP servers that were actually useful, we needed to solve a more fundamental problem: structured data about our services and infrastructure. We need our agents to understand context outside the code base, like who owns what, how services depend on each other, where the documentation lives, and what databases a service talks to.

We run Backstage, the open-source internal developer portal originally built by Spotify, as our service catalog. It’s self-hosted (not on Cloudflare products, for the record) and it tracks things like:

  • 2,055 services, 167 libraries, and 122 packages

  • 228 APIs with schema definitions

  • 544 systems (products) across 45 domains

  • 1,302 databases, 277 ClickHouse tables, 173 clusters

  • 375 teams and 6,389 users with ownership mappings

  • Dependency graphs connecting services to the databases, Kafka topics, and cloud resources they rely on

Our Backstage MCP server (13 tools) is available through our MCP Portal, and an agent can look up who owns a service, check what it depends on, find related API specs, and pull Tech Insights scores, all without leaving the coding session.

Without this structured data, agents are working blind. They can read the code in front of them, but they can’t see the system around it. The catalog turns individual repos into a connected map of the engineering organization.

AGENTS.md: getting thousands of repos ready for AI

Early in the rollout, we kept seeing the same failure mode: coding agents produced changes that looked plausible and were still wrong for the repo. Usually the problem was local context: the model didn’t know the right test command, the team’s current conventions, or which parts of the codebase were off-limits. That pushed us toward AGENTS.md: a short, structured file in each repo that tells coding agents how the codebase actually works and forces teams to make that context explicit.

What AGENTS.md looks like

We built a system that generates AGENTS.md files across our GitLab instance. Because these files sit directly in the model’s context window, we wanted them to stay short and high-signal. A typical file looks like this:

# AGENTS.md

## Repository
- Runtime: cloudflare workers
- Test command: `pnpm test`
- Lint command: `pnpm lint`

## How to navigate this codebase
- All cloudflare workers  are in src/workers/, one file per worker
- MCP server definitions are in src/mcp/, each tool in a separate file
- Tests mirror source: src/foo.ts -> tests/foo.test.ts

## Conventions
- Testing: use Vitest with `@cloudflare/vitest-pool-workers` (Codex: RFC 021, RFC 042)
- API patterns: Follow internal REST conventions (Codex: API-REST-01)

## Boundaries
- Do not edit generated files in `gen/`
- Do not introduce new background jobs without updating `config/`

## Dependencies
- Depends on: auth-service, config-service
- Depended on by: api-gateway, dashboard

When an agent reads this file, it doesn’t have to infer the repo from scratch. It knows how the codebase is organized, which conventions to follow and which Engineering Codex rules apply.

How we generate them at scale

The generator pipeline pulls entity metadata from our Backstage service catalog (ownership, dependencies, system relationships), analyzes the repository structure to detect the language, build system, test framework, and directory layout, then maps the detected stack to relevant Engineering Codex standards. A capable model then generates the structured document, and the system opens a merge request so the owning team can review and refine it.

We’ve processed roughly 3,900 repositories this way. The first pass wasn’t always perfect, especially for polyglot repos or unusual build setups, but even that baseline was much better than asking agents to infer everything from scratch.

The initial merge request solved the bootstrap problem, but keeping these files current mattered just as much. A stale AGENTS.md can be worse than no file at all. We closed that loop with the AI Code Reviewer, which can flag when repository changes suggest that AGENTS.md should be updated.

Act 3: The enforcement layer

The AI Code Reviewer

Every merge request at Cloudflare gets an AI code review. Integration is straightforward: teams add a single CI component to their pipeline, and from that point every MR is reviewed automatically.

We use GitLab’s self-hosted solution as our CI/CD platform. The reviewer is implemented as a GitLab CI component that teams include in their pipeline. When an MR is opened or updated, the CI job runs OpenCode with a multi-agent review coordinator. The coordinator classifies the MR by risk tier (trivial, lite, or full) and delegates to specialized review agents: code quality, security, codex compliance, documentation, performance, and release impact. Each agent connects to the AI Gateway for model access, pulls Engineering Codex rules from a central repo, and reads the repository’s AGENTS.md for codebase context. Results are posted back as structured MR comments.

A separate Workers-based config service handles centralized model selection per reviewer agent, so we can shift models without changing the CI template. The review process itself runs in the CI runner and is stateless per execution.

The output format


We spent time getting the output format right. Reviews are broken into categories (Security, Code Quality, Performance) so engineers can scan headers rather than reading walls of text. Each finding has a severity level (Critical, Important, Suggestion, or Optional Nits) that makes it immediately clear what needs attention versus what’s informational.

The reviewer maintains context across iterations. If it flagged something in a previous review round that has since been fixed, it acknowledges that rather than re-raising the same issue. And when a finding maps to an Engineering Codex rule, it cites the specific rule ID, turning an AI suggestion into a reference to an organizational standard.

Workers AI handles about 15% of the reviewer’s traffic, primarily for documentation review tasks where Kimi K2.5 performs well at a fraction of the cost of frontier models. Models like Opus 4.6 and GPT 5.4 handle security-sensitive and architecturally complex reviews where reasoning capability matters most.

Over the last 30 days:

  • 100% AI code reviewer coverage across all repos on our standard CI pipeline.

  • 5.47M AI Gateway requests

  • 24.77B tokens processed

We’re releasing a detailed technical blog post alongside this one that covers the reviewer’s internal architecture, including how we route between models, the multi-agent orchestration, and the cost optimization strategies we’ve developed.

Engineering Codex: engineering standards as agent skills

The Engineering Codex is Cloudflare’s new internal standards system where our core engineering standards live. We have a multi-stage AI distillation process, which outputs a set of codex rules (“If you need X, use Y. You must do X, if you are doing Y or Z.”) along with an agent skill that uses progressive disclosure and nested hierarchical information directories and links across markdown files. 

This skill is available for engineers to use locally as they build with prompts like “how should I handle errors in my Rust service?” or “review this TypeScript code for compliance.” Our Network Firewall team audited rampartd using a multi-agent consensus process where every requirement was scored COMPLIANT, PARTIAL, or NON-COMPLIANT with specific violation details and remediation steps reducing what previously required weeks of manual work to a structured, repeatable process.

At review time, the AI Code Reviewer cites specific Codex rules in its feedback.


 AI Code Review: showing categorized findings (Codex Compliance in this case) noting the codex RFC violation.

None of these pieces are especially novel on their own. Plenty of companies run service catalogs, ship reviewer bots, or publish engineering standards. The difference is the wiring. When an agent can pull context from Backstage, read AGENTS.md for the repo it’s editing, and get reviewed against Codex rules by the same toolchain, the first draft is usually close enough to ship. That wasn’t true six months ago.

The scoreboard

From launching this effort to 93% R&D adoption took less than a year.


Company-wide adoption (Feb 5 – April 15, 2026):

Metric

Value

Active users

3,683 (60% of the company)

R&D team adoption

93%

AI messages

47.95M

Teams with AI activity

295

OpenCode messages

27.08M

Windsurf messages

434.9K

AI Gateway (last 30 days, combined):

Metric

Value

Requests

20.18M

Tokens

241.37B

Workers AI (last 30 days):

Metric

Value

Input tokens

51.47B

Output tokens

361.12M

What’s next: background agents

The next evolution in our internal engineering stack will include background agents: agents that can be spun up on demand with the same tools available locally (MCP portal, git, test runners) but running entirely in the cloud. The architecture uses Durable Objects and the Agents SDK for orchestration, delegating to Sandbox containers when the job requires a full development environment like cloning a repo, installing dependencies, or running tests. The Sandbox SDK went GA during Agents Week.

Long-running agents, shipped natively into the Agents SDK during Agents Week, solve the durable session problem that previously required workarounds. The SDK now supports sessions that run for extended periods without eviction, enough for an agent to clone a large repo, run a full test suite, iterate on failures, and open a MR in a single session.

This represents an eleven-month effort to rethink not just how code gets written, but how it gets reviewed, how standards are enforced, and how changes ship safely across thousands of repos. Every layer runs on the same products our customers use.

Start building

Agents Week just shipped everything you need. The platform is here.

npx create-cloudflare@latest --template cloudflare/agents-starter

That agents starter gets you running. The diagram below is the full architecture for when you’re ready to grow it, your tools layer on top (chatbot, web UI, CLI, browser extension), the Agents SDK handling session state and orchestration in the middle, and the Cloudflare services you call from it underneath.


Docs: Agents SDK · Sandbox SDK · AI Gateway · Workers AI · Workflows · Code Mode · MCP on Cloudflare

Repos: cloudflare/agents · cloudflare/sandbox-sdk · cloudflare/mcp-server-cloudflare · cloudflare/skills

For more on how we’re using AI at Cloudflare, read the post on our process for AI Code Review. And check out everything we shipped during Agents Week.

We’d love to hear what you build. Find us on Discord, X, and Bluesky.

Ayush Thakur built the AGENTS.md system and the AI Gateway integration for the OpenCode infrastructure, Scott Roemeschke is the Engineering Manager of the Developer Productivity team at Cloudflare, Rajesh Bhatia leads the Productivity Platform function at Cloudflare. This post was a collaborative effort across the Devtools team, with help from volunteers across the company through the iMARS (Internal MCP Agent/Server Rollout Squad) tiger team.

Building the agentic cloud: everything we launched during Agents Week 2026

Post Syndicated from Ming Lu original https://blog.cloudflare.com/agents-week-in-review/

Today marks the end of our first Agents Week, an innovation week dedicated entirely to the age of agents. It couldn’t have been more timely: over the past year, agents have swiftly changed how people work. Coding agents are helping developers ship faster than ever. Support agents resolve tickets end-to-end. Research agents validate hypotheses across hundreds of sources in minutes. And people aren’t just running one agent: they’re running several in parallel and around the clock.

As Cloudflare’s CTO Dane Knecht and VP of Product Rita Kozlov noted in our welcome to Agents Week post, the potential scale of agents is staggering: If even a fraction of the world’s knowledge workers each run a few agents in parallel, you need compute capacity for tens of millions of simultaneous sessions. The one-app-serves-many-users model the cloud was built on doesn’t work for that. But that’s exactly what developers and businesses want to do: build agents, deploy them to users, and run them at scale.

Getting there means solving problems across the entire stack. Agents need compute that scales from full operating systems to lightweight isolates. They need security and identity built into how they run.  They need an agent toolbox: the right models, tools, and context to do real work. All the code that agents generate needs a clear path from afternoon prototype to production app. And finally, as agents drive a growing share of Internet traffic, the web itself needs to adapt for the emerging agentic web. Turns out, the containerless, serverless compute platform we launched eight years ago with Workers was ready-made for this moment. Since then, we’ve grown it into a full platform, and this week we shipped the next wave of primitives purpose-built for agents, organized around exactly those problems.

We are here to create Cloud 2.0 — the agentic cloud. Infrastructure designed for a world where agents are a primary workload. 

Here’s a list of everything we announced this week — we wouldn’t want you to miss a thing.

Compute

It starts with compute. Agents need somewhere to run, and somewhere to store and run the code they write. Not all agents need the same thing: some need a full operating system to install packages and run terminal commands, most need something lightweight that starts in milliseconds and scales to millions. This week we shipped the environments to run them, as well as a new Git-compatible workspace for agents:

Announcement

Summary

Artifacts: Versioned storage that speaks Git

Give your agents, developers, and automations a home for code and data. We’ve just launched Artifacts: Git-compatible versioned storage built for agents. Create tens of millions of repos, fork from any remote, and hand off a URL to any Git client.

Agents have their own computers with Sandboxes GA

Cloudflare Sandboxes give AI agents a persistent, isolated environment: a real computer with a shell, a filesystem, and background processes that starts on demand and picks up exactly where it left off.

Dynamic, identity-aware, and secure: egress controls for Sandboxes

Outbound Workers for Sandboxes provide a programmable, zero-trust egress proxy for AI agents. This allows developers to inject credentials and enforce dynamic security policies without exposing sensitive tokens to untrusted code.

Durable Objects in Dynamic Workers: Give each AI-generated app its own database

Durable Object Facets allows Dynamic Workers to instantiate Durable Objects with their own isolated SQLite databases. This enables developers to build platforms that run persistent, stateful code generated on-the-fly.

Rearchitecting the Workflows control plane for the agentic era

Cloudflare Workflows, a durable execution engine for multi-step applications, now supports 50,000 concurrency and 300 creation rate limits through a rearchitectured control plane, helping scale to meet the use cases for durable background agents.


Security

Running agents and their code is only half the challenge. Agents connect to private networks, access internal services, and take autonomous actions on behalf of users. When anyone in an organization can spin up their own agents, security can’t be an afterthought. It has to be the default. This week, we launched the tools to make that easy.

Announcement

Summary

Secure private networking for everyone: users, nodes, agents, Workers — introducing Cloudflare Mesh

Cloudflare Mesh provides secure, private network access for users, nodes, and autonomous AI agents. By integrating with Workers VPC, developers can now grant agents scoped access to private databases and APIs without manual tunnels.

Managed OAuth for Access: make internal apps agent-ready in one click

Managed OAuth for Cloudflare Access helps AI agents securely navigate internal applications. By adopting RFC 9728, agents can authenticate on behalf of users without using insecure service accounts.

Securing non-human identities: automated revocation, OAuth, and scoped permissions

Cloudflare is introducing scannable API tokens, enhanced OAuth visibility, and GA for resource-scoped permissions. These tools help developers implement a true least-privilege architecture while protecting against credential leakage.

Scaling MCP adoption: our reference architecture for enterprise MCP deployments

We share Cloudflare’s internal strategy for governing MCP using Access, AI Gateway, and MCP server portals. We also launch Code Mode to slash token costs and recommend new rules for detecting Shadow MCP in Cloudflare Gateway.


Agent Toolbox

A capable agent needs to be able to think and remember, communicate, and see. This means being powered with the right models, with access to the right tools and the right context for their task at hand. This week we shipped the primitives — inference, search, memory, voice, email, and a browser — that turn an agent into something that actually gets work done.

Announcement

Summary

Project Think: building the next generation of AI agents on Cloudflare

Announcing a preview of the next edition of the Agents SDK — from lightweight primitives to a batteries-included platform for AI agents that think, act, and persist.

Add voice to your agent

An experimental voice pipeline for the Agents SDK enables real-time voice interactions over WebSockets. Developers can now build agents with continuous STT and TTS in just ~30 lines of server-side code.

Cloudflare Email Service: now in public beta. Ready for your agents

Agents are becoming multi-channel. That means making them available wherever your users already are — including the inbox. Cloudflare Email Service enters public beta with the infrastructure layer to make that easy: send, receive, and process email natively from your agents.

Cloudflare’s AI platform: an inference layer designed for agents 

We’re building Cloudflare into a unified inference layer for agents, letting developers call models from 14+ providers. New features include Workers binding for running third-party models and an expanded catalog with multimodal models.

Building the foundation for running extra-large language models

We built a custom technology stack to run fast large language models on Cloudflare’s infrastructure. This post explores the engineering trade-offs and technical optimizations required to make high-performance AI inference accessible.

Unweight: how we compressed an LLM 22% without sacrificing quality

Running large LLMs across Cloudflare’s network requires us to be smarter and more efficient about GPU memory bandwidth. That’s why we developed Unweight, a lossless inference-time compression system that achieves up to a 22% model footprint reduction, so that we can deliver faster and cheaper inference than ever before. 

Agents that remember: introducing Agent Memory

Cloudflare Agent Memory is a managed service that gives AI agents persistent memory, allowing them to recall what matters, forget what doesn’t, and get smarter over time.

AI Search: the search primitive for your agents

AI Search is the search primitive for your agents. Create instances dynamically, upload files, and search across instances with hybrid retrieval and relevance boosting. Just create a search instance, upload, and search.

Browser Run: give your agents a browser

Browser Rendering is now Browser Run, with Live View, Human in the Loop, CDP access, session recordings, and 4x higher concurrency limits for AI agents.


Prototype to production

The best infrastructure is also one that’s easy to use. We want to meet developers and their agents where they’re already working: in the terminal, in the editor, in a prompt, and make the full Cloudflare platform accessible without context-switching.

Announcement

Summary

Building a CLI for all of Cloudflare

We’re introducing cf, a new unified CLI designed for consistency across the Cloudflare platform, alongside Local Explorer for debugging local data. These tools simplify how developers and AI agents interact with our nearly 3,000 API operations.

Introducing Agent Lee – a new interface to the Cloudflare stack

Agent Lee is an in-dashboard agent that shifts Cloudflare’s interface from manual tab-switching to a single prompt. Using sandboxed TypeScript, it helps you troubleshoot and manage your stack as a grounded technical collaborator.

Introducing Flagship: feature flags built for the age of AI

Introducing Flagship, a native feature flag service built on Cloudflare’s global network to eliminate the latency of third-party providers. By using KV and Durable Objects, Flagship allows for sub-millisecond flag evaluation.

Deploy Postgres and MySQL databases with PlanetScale + Workers

Learn how to deploy PlanetScale Postgres and MySQL databases via Cloudflare and connect Cloudflare Workers.

Register domains wherever you build: Cloudflare Registrar API now in beta

The Cloudflare Registrar API is now in beta. Developers and AI agents can search, check availability, and register domains at cost directly from their editor, their terminal, or their agent — without leaving their workflow.


Agentic Web

As more agents come online, they’re still browsing an Internet that was built for people. Existing websites need new tools to control what bots can access their content, package and present it for agents, and measure how ready they are for this shift.

Announcement

Summary

Introducing the Agent Readiness score. Is your site agent-ready?

The Agent Readiness score can help site owners understand how well their websites support AI agents. Here we explore new standards, share Radar data, and detail how we made Cloudflare’s docs the most agent-friendly on the web.

Redirects for AI Training enforces canonical content

Soft directives don’t stop crawlers from ingesting deprecated content. Redirects for AI Training allows anybody on Cloudflare to redirect verified crawlers to canonical pages with one toggle and no origin changes.

Agents Week: Network performance update

By migrating our request handling layer to a Rust-based architecture called FL2, Cloudflare has increased its performance lead to 60% of the world’s top networks. We use real-user measurements and TCP connection trimeans to ensure our data reflects the actual experience of people on the Internet

Shared dictionary compression that keeps up with the agentic web

We give you a sneak peek of our support for shared compression dictionaries, show you how it improves page load times, and reveal when you’ll be able to try the beta yourself.


That’s a wrap

Agents Week 2026 is ending, but the agentic cloud is just getting started. Everything we shipped this week — from compute and security to the agent toolbox and the agentic web — is the foundation. We’re going to keep building on it to give you everything you need to build what’s next.

We also have more blog posts coming out today and tomorrow to continue the story, so keep an eye out for the latest at our blog.

If you’re building on any of what we announced this week, we want to hear about it. Come find us on X or Discord, or head to the developer documentation.


Cloudflare’s AI Platform: an inference layer designed for agents

Post Syndicated from Ming Lu original https://blog.cloudflare.com/ai-platform/

AI models are changing quickly: the best model to use for agentic coding today might in three months be a completely different model from a different provider. On top of this, real-world use cases often require calling more than one model. Your customer support agent might use a fast, cheap model to classify a user’s message; a large, reasoning model to plan its actions; and a lightweight model to execute individual tasks.

This means you need access to all the models, without tying yourself financially and operationally to a single provider. You also need the right systems in place to monitor costs across providers, ensure reliability when one of them has an outage, and manage latency no matter where your users are.

These challenges are present whenever you’re building with AI, but they get even more pressing when you’re building agents. A simple chatbot might make one inference call per user prompt. An agent might chain ten calls together to complete a single task and suddenly, a single slow provider doesn’t add 50ms, it adds 500ms. One failed request isn’t a retry, but suddenly a cascade of downstream failures. 

Since launching AI Gateway and Workers AI, we’ve seen incredible adoption from developers building AI-powered applications on Cloudflare and we’ve been shipping fast to keep up! In just the past few months, we’ve refreshed the dashboard, added zero-setup default gateways, automatic retries on upstream failures, and more granular logging controls. Today, we’re making Cloudflare into a unified inference layer: one API to access any AI model from any provider, built to be fast and reliable. 

One catalog, one unified endpoint

Starting today, you can call third-party models using the same AI.run() binding you already use for Workers AI. If you’re using Workers, switching from a Cloudflare-hosted model to one from OpenAI, Anthropic, or any other provider is a one-line change. 

const response = await env.AI.run('anthropic/claude-opus-4-6',{
input: 'What is Cloudflare?',
}, {
gateway: { id: "default" },
});

For those who don’t use Workers, we’ll be releasing REST API support in the coming weeks, so you can access the full model catalog from any environment.

We’re also excited to share that you’ll now have access to 70+ models across 12+ providers — all through one API, one line of code to switch between them, and one set of credits to pay for them. And we’re quickly expanding this as we go.

You can browse through our model catalog to find the best model for your use case, from open-source models hosted on Cloudflare Workers AI to proprietary models from the major model providers. We’re excited to be expanding access to models from Alibaba Cloud, AssemblyAI, Bytedance, Google, InWorld, MiniMax, OpenAI, Pixverse, Recraft, Runway, and Vidu — who will provide their models through AI Gateway. Notably, we’re expanding our model offerings to include image, video, and speech models so that you can build multimodal applications


Accessing all your models through one API also means you can manage all your AI spend in one place. Most companies today are calling an average of 3.5 models across multiple providers, which means no one provider is able to give you a holistic view of your AI usage. With AI Gateway, you’ll get one centralized place to monitor and manage AI spend.

By including custom metadata with your requests, you can get a breakdown of your costs on the attributes that you care about most, like spend by free vs. paid users, by individual customers, or by specific workflows in your app.

const response = await env.AI.run('@cf/moonshotai/kimi-k2.5',
      {
prompt: 'What is AI Gateway?'
      },
      {
metadata: { "teamId": "AI", "userId": 12345 }
      }
    );

Bring your own model

AI Gateway gives you access to models from all the providers through one API. But sometimes you need to run a model you’ve fine-tuned on your own data or one optimized for your specific use case. For that, we are working on letting users bring their own model to Workers AI. 

The overwhelming majority of our traffic comes from dedicated instances for Enterprise customers who are running custom models on our platform, and we want to bring this to more customers. To do this, we leverage Replicate’s Cog technology to help you containerize machine learning models.

Cog is designed to be quite simple: all you need to do is write down dependencies in a cog.yaml file, and your inference code in a Python file. Cog abstracts away all the hard things about packaging ML models, such as CUDA dependencies, Python versions, weight loading, etc.

Example of a cog.yaml file:

build:
  python_version: "3.13"
  python_requirements: requirements.txt
predict: "predict.py:Predictor"

Example of a predict.py file, which has a function to set up the model and a function that runs when you receive an inference request (a prediction):

from cog import BasePredictor, Path, Input
import torch

class Predictor(BasePredictor):
    def setup(self):
        """Load the model into memory to make running multiple predictions efficient"""
        self.net = torch.load("weights.pth")

    def predict(self,
            image: Path = Input(description="Image to enlarge"),
            scale: float = Input(description="Factor to scale image by", default=1.5)
    ) -> Path:
        """Run a single prediction on the model"""
        # ... pre-processing ...
        output = self.net(input)
        # ... post-processing ...
        return output

Then, you can run cog build to build your container image, and push your Cog container to Workers AI. We will deploy and serve the model for you, which you then access through your usual Workers AI APIs. 

We’re working on some big projects to be able to bring this to more customers, like customer-facing APIs and wrangler commands so that you can push your own containers, as well as faster cold starts through GPU snapshotting. We’ve been testing this internally with Cloudflare teams and some external customers who are guiding our vision. If you’re interested in being a design partner with us, please reach out! Soon, anyone will be able to package their model and use it through Workers AI.

The fast path to first token

Using Workers AI models with AI Gateway is particularly powerful if you’re building live agents – where a user’s perception of speed hinges on time to first token or how quickly the agent starts responding, rather than how long the full response takes. Even if total inference is 3 seconds, getting that first token 50ms faster makes the difference between an agent that feels zippy and one that feels sluggish.

Cloudflare’s network of data centers in 330 cities around the world means AI Gateway is positioned close to both users and inference endpoints, minimizing the network time before streaming begins.

Workers AI also hosts open-source models on its public catalog, which now includes large models purpose-built for agents, including Kimi K2.5 and real-time voice models. When you call these Cloudflare-hosted models through AI Gateway, there’s no extra hop over the public Internet since your code and inference run on the same global network, giving your agents the lowest latency possible.

Built for reliability with automatic failover

When building agents, speed is not the only factor that users care about – reliability matters too. Every step in an agent workflow depends on the steps before it. Reliable inference is crucial for agents because one call failing can affect the entire downstream chain. 

Through AI Gateway, if you’re calling a model that’s available on multiple providers and one provider goes down, we’ll automatically route to another available provider without you having to write any failover logic of your own. 

If you’re building long-running agents with Agents SDK, your streaming inference calls are also resilient to disconnects. AI Gateway buffers streaming responses as they’re generated, independently of your agent’s lifetime. If your agent is interrupted mid-inference, it can reconnect to AI Gateway and retrieve the response without having to make a new inference call or paying twice for the same output tokens. Combined with the Agents SDK’s built-in checkpointing, the end user never notices.

Replicate

The Replicate team has officially joined our AI Platform team, so much so that we don’t even consider ourselves separate teams anymore. We’ve been hard at work on integrations between Replicate and Cloudflare, which include bringing all the Replicate models onto AI Gateway and replatforming the hosted models onto Cloudflare infrastructure. Soon, you’ll be able to access the models you loved on Replicate through AI Gateway, and host the models you deployed on Replicate on Workers AI as well.

Get started

To get started, check out our documentation for AI Gateway or Workers AI. Learn more about building agents on Cloudflare through Agents SDK

Watch on Cloudflare TV

Building the foundation for running extra-large language models

Post Syndicated from Michelle Chen original https://blog.cloudflare.com/high-performance-llms/

An agent needs to be powered by a large language model. A few weeks ago, we announced that Workers AI is officially entering the arena for hosting large open-source models like Moonshot’s Kimi K2.5. Since then, we’ve made Kimi K2.5 3x faster and have more model additions in-flight. These models have been the backbone of a lot of the agentic products, harnesses, and tools that we have been launching this week. 

Hosting AI models is an interesting challenge: it requires a delicate balance between software and very, very expensive hardware. At Cloudflare, we’re good at squeezing every bit of efficiency out of our hardware through clever software engineering. This is a deep dive on how we’re laying the foundation to run extra-large language models.

Hardware configurations

As we mentioned in our previous Kimi K2.5 blog post, we’re using a variety of hardware configurations in order to best serve models. A lot of hardware configurations depend on the size of inputs and outputs that users are sending to the model. For example, if you are using a model to write fanfiction, you might give it a few small prompts (input tokens) while asking it to generate pages of content (output tokens). 

Conversely, if you are running a summarization task, you might be sending in hundreds of thousands of input tokens, but only generating a small summary with a few thousand output tokens. Presented with these opposing use cases, you have to make a choice — should you tune your model configuration so it’s faster at processing input tokens, or faster at generating output tokens?

When we launched large language models on Workers AI, we knew that most of the use cases would be used for agents. With agents, you send in a large number of input tokens. It starts off with a large system prompt, all the tools, MCPs. With the first user prompt, that context keeps growing. Each new prompt from the user sends a request to the model, which consists of everything that was said before — all the previous user prompts, assistant messages, code generated, etc. For Workers AI, that means we had to focus on two things: fast input token processing and fast tool calling.

Prefill decode (PD) disaggregation

One hardware configuration that we use to improve performance and efficiency is disaggregated prefill. There are two stages to processing an LLM request: prefill, which processes the input tokens and populates the KV cache, and decode, which generates output tokens. Prefill is usually compute bound, while decode is memory bound. This means that the parts of the GPU that are used in each stage are different, and since prefill is always done before decode, the stages block one another. Ultimately, it means that we are not efficiently utilizing all of our GPU power if we do both prefill and decode on a single machine.

With prefill decode disaggregation, separate inference servers are run for each stage. First, a request is sent to the prefill stage which performs prefill and stores it in its KV cache. Then the same request is sent to the decode server, with information about how to transfer the KV cache from the prefill server and begin decoding. This has a number of advantages, because it allows the servers to be tuned independently for the role they are performing, scaled to account for more input-heavy or output-heavy traffic, or even to run on heterogeneous hardware.

This architecture requires a relatively complex load balancer to achieve. Beyond just routing the requests as described above, it must rewrite the responses (including streaming SSE) of the decode server to include information from the prefill server such as cached tokens. To complicate matters, different inference servers require different information to initiate the KV cache transfer. We extended this to implement token-aware load balancing, in which there is a pool of prefill and decode endpoints, and the load balancer estimates how many prefill or decode tokens are in-flight to each endpoint in the pool and attempts to spread this load evenly. 

After our public model launch, our input/output patterns changed drastically again. We took the time to analyze our new usage patterns and then tuned our configuration to fit our customer’s use cases.

Here’s a graph of our p90 Time to First Token drop after shifting traffic to our new PD disaggregated architecture, whilst request volume increased, using the same quantity of GPUs. We see a significant improvement in the tail latency variance.


Similarly, p90 time per token went from ~100 ms with high variance to 20-30 ms, a 3x improvement in intertoken latency.


Prompt Caching

Since agentic use cases usually have long contexts, we optimize for efficient prompt caching in order to not recompute input tensors on every turn. We leverage a header called x-session-affinity in order to help requests route to the right region that previously had the computed input tensors. We wrote about this in our original blog post about launching large LLMs on Workers AI. We added session affinity headers to popular agent harnesses like OpenCode, where we noticed a significant increase in total throughput. A small difference in prompt caching from our users can sum to a factor of additional GPUs needed to run a model. While we have KV-aware routing internally, we also rely on clients sending the x-session-affinity in order to be explicit about prompt caching. We incentivize the use of the header by offering discounted cached tokens. We highly encourage users to leverage prompt caching in order to have faster inference and cheaper pricing.


We worked with our heaviest internal users to adopt this header. The result was an increase in input token cache hit ratios from 60% to 80% during peak times. This significantly increases the request throughput that we can handle, while offering better performance for interactive or time-sensitive sessions like OpenCode or AI code reviews.

KV-cache optimization

As we’re serving larger models now, one instance can span multiple GPUs. This means that we had to find an efficient way to share KV cache across GPUs. KV cache is where all the input tensors from prefill (result of prompts in a session) are stored, and initially lives in the VRAM of a GPU. Every GPU has a fixed VRAM size, but if your model instance requires multiple GPUs, there needs to be a way for the KV cache to live across GPUs and talk to each other. To achieve this for Kimi, we leveraged Moonshot AI’s Mooncake Transfer Engine and Mooncake Store.

Mooncake’s Transfer Engine is a high-performance data transfer framework. It works with different Remote Direct Memory Access (RDMA) protocols such as NVLink and NVMe over Fabric, which enables direct memory-to-memory data transfer without involving the CPU. It improves the speed of transferring data across multiple GPU machines, which is particularly important in multi-GPU and multi-node configurations for models. 

When paired with LMCache or SGLang HiCache, the cache is shared across all nodes in the cluster, allowing a prefill node to identify and re-use a cache from a previous request that was originally pre-filled on a different node. This eliminates the need for session aware routing within a cluster and allows us to load balance the traffic much more evenly. Mooncake Store also allows us to extend the cache beyond GPU VRAM, and leverage NVMe storage. This extends the time that sessions remain in cache, improving our cache hit ratio and allowing us to handle more traffic and offer better performance to users.

Speculative decoding

LLMs work by predicting the next token in a sequence, based on the tokens that came before it. With a naive implementation, models only predict the next n token, but we can actually make it predict the next n+1, n+2… tokens in a single forward pass of the model. This popular technique is known as speculative decoding, which we’ve written about in a previous post on Workers AI. 


With speculative decoding, we leverage a smaller LLM (the draft model) to generate a few candidate tokens for the target model to choose from. The target model then just has to select from a small pool of candidate tokens in a single forward pass. Validating the tokens is faster and less computationally expensive than using the larger target model to generate the tokens. However, quality is still upheld as the target model ultimately has to accept or reject the draft tokens.

In agentic use cases, speculative decoding really shines because of the volume of tool calls and structured outputs that models need to generate. A tool call is largely predictable — you know there will be a name, description, and it’s wrapped in a JSON envelope.

To do this with Kimi K2.5, we leverage NVIDIA’s EAGLE-3 (Extrapolation Algorithm for Greater Language-model Efficiency) draft model. The levers for tuning speculative decoding include the number of future tokens to generate. As a result, we’re able to achieve high-quality inference while speeding up tokens per second throughput.

Infire: our proprietary inference engine

As we announced during Birthday Week in 2025, Cloudflare has a proprietary inference engine, Infire, that makes machine learning models faster. Infire is an inference engine written in Rust, designed to support Cloudflare’s unique challenges with inference given our distributed global network. We’ve extended Infire support for this new class of large language models we are planning to run, which meant we had to build a few new features to make it all work.

Multi-GPU support

Large language models like Kimi K2.5 are over 1 trillion parameters, which is about 560GB of model weights. A typical H100 has about 80GB of VRAM and the model weights need to be loaded in GPU memory in order to run. This means that a model like Kimi K2.5 needs at least 8 H100s in order to load the model into memory and run — and that’s not even including the extra VRAM you would need for KV Cache, which includes your context window.

Since we initially launched Infire, we had to add support for multi-GPU, letting the inference engine run across multiple GPUs in either pipeline-parallel or tensor-parallel modes with expert-parallelism supported as well.

For pipeline parallelism, Infire attempts to properly load balance all stages of the pipeline, in order to prevent the GPUs of one stage from starving while other stages are executing. On the other hand, for tensor parallelism, Infire optimizes for reducing cross-GPU communication, making it as fast as possible. For most models, utilizing both pipeline parallelism and tensor parallelism in tandem provides the best balance of throughput and latency.

Even lower memory overhead

While already having much lower GPU memory overhead than vLLM, we optimized Infire even further, tightening the memory required for internal state like activations. Currently Infire is capable of running Llama 4 Scout on just two H200 GPUs with more than 56 GiB remaining for KV-cache, sufficient for more than 1.2m tokens. Infire is also capable of running Kimi K2.5 on 8 H100 GPUs (yes that is H100), with more than 30 GiB still available for KV-cache. In both cases you would have trouble even booting vLLM in the first place.

Faster cold-starts

While adding multi-GPU support, we identified additional opportunities to improve boot times. Even for the largest models, such as Kimi K2.5, Infire can begin serving requests in under 20 seconds. The load times are only bounded by the drive speed.

Maximizing our hardware for faster throughput

Investing in our proprietary inference engine enables us to maximize our hardware by getting up to 20% higher tokens per second throughput on unconstrained systems, and also enabling us to use lower-end hardware to run the latest models, where it was previously completely infeasible.

The journey doesn’t end

New technologies, research, and models come out on a weekly basis for the machine learning community. We’re continuously optimizing our technology stack in order to provide high-quality, performant inference for our customers while operating our GPUs efficiently. If these sound like interesting challenges for you – we’re hiring!

Cloudflare Email Service: now in public beta. Ready for your agents

Post Syndicated from Thomas Gauvin original https://blog.cloudflare.com/email-for-agents/

Email is the most accessible interface in the world. It is ubiquitous. There’s no need for a custom chat application, no custom SDK for each channel. Everyone already has an email address, which means everyone can already interact with your application or agent. And your agent can interact with anyone.

If you are building an application, you already rely on email for signups, notifications, and invoices. Increasingly, it is not just your application logic that needs this channel. Your agents do, too. During our private beta, we talked to developers who are building exactly this: customer support agents, invoice processing pipelines, account verification flows, multi-agent workflows. All built on top of email. The pattern is clear: email is becoming a core interface for agents, and developers need infrastructure purpose-built for it.

Cloudflare Email Service is that piece. With Email Routing, you can receive email to your application or agent. With Email Sending, you can reply to emails or send outbounds to notify your users when your agents are done doing work. And with the rest of the developer platform, you can build a full email client and Agents SDK onEmail hook as native functionality. 

Today, as part of Agents Week, Cloudflare Email Service is entering public beta, allowing any application and any agent to send emails. We are also completing the toolkit for building email-native agents: 

  • Email Sending binding, available from your Workers and the Agents SDK 

  • A new Email MCP server

  • Wrangler CLI email commands

  • Skills for coding agents

  • An open-source agentic inbox reference app

Email Sending: now in public beta

Email Sending graduates from private beta to public beta today. You can now send transactional emails directly from Workers with a native Workers binding — no API keys, no secrets management.

export default {
  async fetch(request, env, ctx) {
    await env.EMAIL.send({
      to: "[email protected]",
      from: "[email protected]",
      subject: "Your order has shipped",
      text: "Your order #1234 has shipped and is on its way."
    });
    return new Response("Email sent");
  },
};

Or send from any platform, any language, using the REST API and our TypeScript, Python, and Go SDKs:

curl "https://api.cloudflare.com/client/v4/accounts/{account_id}/email-service/send" \
   --header "Authorization: Bearer <API_TOKEN>" \
   --header "Content-Type: application/json" \
   --data '{
     "to": "[email protected]",
     "from": "[email protected]",
     "subject": "Your order has shipped",
     "text": "Your order #1234 has shipped and is on its way."
   }'

Sending email that actually reaches inboxes usually means wrestling with SPF, DKIM, and DMARC records. When you add your domain to Email Service, we configure all of it automatically. Your emails are authenticated and delivered, not flagged as spam. And because Email Service is a global service built on Cloudflare’s network, your emails are delivered with low latency anywhere in the world.

Combined with Email Routing, which has been free and available for years, you now have complete bidirectional email within a single platform. Receive an email, process it in a Worker, and reply, all without leaving Cloudflare.

For the full deep dive on Email Sending, refer to our Birthday Week announcement. The rest of this post describes what Email Service unlocks for agents.

Agents SDK: your agent is email-native

The Agents SDK for building agents on Cloudflare already has a first-class onEmail hook for receiving and processing inbound email. But until now, your agent could only reply synchronously, or send emails to members of your Cloudflare account. 

With Email Sending, that constraint is gone. This is the difference between a chatbot and an agent.


Email agents receive a message, orchestrate work across the platform, and respond asynchronously.

A chatbot responds in the moment or not at all. An agent thinks, acts, and communicates on its own timeline. With Email Sending, your agent can receive a message, spend an hour processing data, check three other systems, and then reply with a complete answer. It can schedule follow-ups. It can escalate when it detects an edge case. It can operate independently. In other words: it can actually do work, not just answer questions. 

Here’s what a support agent looks like with the full pipeline — receive, persist, and reply:

import { Agent, routeAgentEmail } from "agents";
import { createAddressBasedEmailResolver, type AgentEmail } from "agents/email";
import PostalMime from "postal-mime";

export class SupportAgent extends Agent {
  async onEmail(email: AgentEmail) {
    const raw = await email.getRaw();
    const parsed = await PostalMime.parse(raw);

   // Persist in agent state
    this.setState({
      ...this.state,
      ticket: { from: email.from, subject: parsed.subject, body: parsed.text, messageId: parsed.messageId },
    });

    // Kick off long running background agent task 
    // Or place a message on a Queue to be handled by another Worker

    // Reply here or in other Worker handler, like a Queue handler
    await this.sendEmail({
      binding: this.env.EMAIL,
      fromName: "Support Agent",
      from: "[email protected]",
      to: this.state.ticket.from,
      inReplyTo: this.state.ticket.messageId,
      subject: `Re: ${this.state.ticket.subject}`,
      text: `Thanks for reaching out. We received your message about "${this.state.ticket.subject}" and will follow up shortly.`
    });
  }
}

export default {
  async email(message, env) {
    await routeAgentEmail(message, env, {
      resolver: createAddressBasedEmailResolver("SupportAgent"),
    });
  },
} satisfies ExportedHandler<Env>;

If you’re new to the Agents SDK’s email capabilities, here’s what’s happening under the hood.

Each agent gets its own identity from a single domain. The address-based resolver routes [email protected] to a “support” agent instance, [email protected] to a “sales” instance, and so on. You don’t need to provision separate inboxes — the routing is built into the address. You can even use sub-addressing ([email protected]) to route to different agent namespaces and instances.

State persists across emails. Because agents are backed by Durable Objects, calling this.setState() means your agent remembers conversation history, contact information, and context across sessions. The inbox becomes the agent’s memory, without needing a separate database or vector store.

Secure reply routing is built in. When your agent sends an email and expects a reply, you can sign the routing headers with HMAC-SHA256 so that replies route back to the exact agent instance that sent the original message. This prevents attackers from forging headers to route emails to arbitrary agent instances — a security concern that most “email for agents” solutions haven’t addressed.

This is the complete email agent pipeline that teams are building from scratch elsewhere: receive email, parse it, classify it, persist state, kick off async workflows, reply or escalate — all within a single Agent class, deployed globally on Cloudflare’s network.

Email tooling for your agents: MCP server, Wrangler CLI, and skills

Email Service isn’t only for agents running on Cloudflare. Agents run everywhere, whether it’s coding agents like Claude Code, Cursor, or Copilot running locally or in remote environments, or production agents running in containers or external clouds. They all need to send email from those environments. We’re shipping three integrations that make Email Service accessible to any agent, regardless of where it runs.

Email is now available through the Cloudflare MCP server, the same Code Mode-powered server that gives agents access to the entire Cloudflare API. With this MCP server, your agent can discover and call the Email endpoints to send and configure emails. You can send an email with a simple prompt:

"Send me a notification email at [email protected] from my staging domain when the build completes"

For agents running on a computer or a sandbox with bash access, the Wrangler CLI solves the MCP context window problem that we discussed in the Code Mode blog post — tool definitions can consume tens of thousands of tokens before your agent even starts processing a single message. With Wrangler, your agent starts with near-zero context overhead and discovers capabilities on demand through `–help` commands. Here is how your agent can send an email via Wrangler:

wrangler email send \
  --to "[email protected]" \
  --from "[email protected]" \
  --subject "Build completed" \
  --text "The build passed. Deployed to staging."

Regardless of whether you give your agent the Cloudflare MCP or the Wrangler CLI, your agent will be able to now send emails on your behalf with just a prompt.

Skills

We are also publishing a Cloudflare Email Service skill. It gives your agents complete guidance: configuring the Workers binding, sending emails via the REST API or SDKs, handling inbound email with Email Routing configuration, building with Agents SDK, and managing email through Wrangler CLI or MCP. It also covers deliverability best practices and how to craft good transactional emails that land in inboxes rather than spam. Drop it into your project and your coding agent has everything needed to build production-ready email on Cloudflare.

Open-sourcing tools for email agents

During the private beta, we also experimented with email agents. It became clear that you often want to keep the human-in-the-loop element to review emails and see what the agent is doing.The best way to do that is to have a fully featured email client with agent automations built-in.

That’s why we built Agentic Inbox: a reference application with full conversation threading, email rendering, receiving and storing emails and their attachments, and automatically replying to emails. It includes a dedicated MCP server built-in, so external agents can draft emails for your review before sending from your agentic-inbox. 


We’re open-sourcing Agentic Inbox as a reference application for how to build a full email application using Email Routing for inbound, Email Sending for outbound, Workers AI for classification, R2 for attachments, and Agents SDK for stateful agent logic. You can deploy it today to get a full inbox, email client and agent for your emails, with the click of a button.

We want email agent tooling to be composable and reusable. Rather than every team rebuilding the same inbound-classify-reply pipeline, start with this reference application. Fork it, extend it, use it as a starting point for your own email agents that fit your workflows.

Try it out today

Email is where the world’s most important workflows live, but for agents, it has often been a difficult channel to reach. With Email Sending now in public beta, Cloudflare Email Service becomes a complete platform for bidirectional communication, making the inbox a first-class interface for your agents.

Whether you’re building a support agent that meets customers in their inbox or a background process that keeps your team updated in real time, your agents now have a seamless way to communicate on a global scale. The inbox is no longer a silo. Now it’s one more place for your agents to be helpful.


Watch on Cloudflare TV

Introducing Agent Lee – a new interface to the Cloudflare stack

Post Syndicated from Kylie Czajkowski original https://blog.cloudflare.com/introducing-agent-lee/

While there have been small improvements along the way, the interface of technical products has not really changed since the dawn of the Internet. It still remains: clicking five pages deep, cross-referencing logs across tabs, and hunting for hidden toggles.

AI gives us the opportunity to rethink all that. Instead of complexity spread over a sprawling graphical user interface: what if you could describe in plain language what you wanted to achieve? 

This is the future — and we’re launching it today. We didn’t want to just put an agent in a dashboard. We wanted to create an entirely new way to interact with our entire platform. Any task, any surface, a single prompt.

Introducing Agent Lee.

Agent Lee is an in-dashboard AI assistant that understands your Cloudflare account. 

It can help you with troubleshooting, which, today, is a manual grind. If your Worker starts returning 503s at 02:00 UTC, finding the root cause: be it an R2 bucket, a misconfigured route, or a hidden rate limit, you’re opening half a dozen tabs and hoping you recognize the pattern. Most developers don’t have a teammate who knows the entire platform standing over their shoulder at 2 a.m. Agent Lee does. 

But it won’t just troubleshoot for you at 2 a.m. Agent Lee will also fix the problem for you on the spot.


Agent Lee has been running in an active beta during which it has served over 18,000 daily users, executing nearly a quarter of a million tool calls per day. While we are confident in its current capabilities and success in production, this is a system we are continuously developing. As it remains in beta, you may encounter unexpected limitations or edge cases as we refine its performance. We encourage you to use the feedback form below to help us make it better every day.

What Agent Lee can do

Agent Lee is built directly into the dashboard and understands the resources in your account. It knows your Workers, your zones, your DNS configuration, your error rates. The knowledge that today lives across six tabs and two browser windows will now live in one place, and you can talk to it.

With natural language, you can use it to:

  • Answer questions about your account: “Show me the top 5 error messages on my Worker.”

  • Debug an issue: “I can’t access my site with the www prefix.”

  • Apply a change: “Enable Access for my domain.”

  • Deploy a resource: “Create a new R2 bucket for my photos and connect it to my Worker.”

Instead of switching between products, you describe what you want to do, and Agent Lee helps you get there with instructions and visualizations. It retrieves context, uses the right tools, and creates dynamic visualizations based on the types of questions you ask. Ask what your error rate looks like over the last 24 hours, and it renders a chart inline, pulling from your actual traffic, not sending you to a separate Analytics page.

Agent Lee isn’t answering FAQ questions — it’s doing real work, against real accounts, at scale. Today, Agent Lee serves ~18,000 daily users, executing ~250k tool calls per day across DNS, Workers, SSL/TLS, R2, Registrar, Cache, Cloudflare Tunnel, API Shield, and more. 

How we built it

Codemode

Rather than presenting MCP tool definitions directly to the model, Agent Lee uses Codemode to convert the tools into a TypeScript API and asks the model to write code that calls it instead.

This works better for a couple of reasons. LLMs have seen a huge amount of real-world TypeScript but very few tool call examples, so they’re more accurate when working in code. For multi-step tasks, the model can also chain calls together in a single script and return only the final result, ultimately skipping the round-trips.

The generated code is sent to an upstream Cloudflare MCP server for sandboxed execution, but it goes through a Durable Object that acts as a credentialed proxy. Before any call goes out, the DO classifies the generated code as read or write by inspecting the method and body. Read operations are proxied directly. Write operations are blocked until you explicitly approve them through the elicitation gate. API keys are never present in the generated code — they’re held inside the DO and injected server-side when the upstream call is made. The security boundary isn’t just a sandbox that gets thrown away; it’s a permission architecture that structurally prevents writes from happening without your approval.

The MCP permission system

Agent Lee connects to Cloudflare’s own MCP server, which exposes two tools: a search tool for querying API endpoints and an execute tool for writing code that performs API requests. This is the surface through which Agent Lee reads your account and, when you approve, writes to it.

Write operations go through an elicitation system that surfaces the approval step before any code executes. Agent Lee cannot skip this step. The permission model is the enforcement layer, and the confirmation prompt you see is not a UX courtesy. It’s the gate.


Built on the same stack you can use

Every primitive Agent Lee is built on is available to all our customers: Agents SDK, Workers AI, Durable Objects, and the same MCP infrastructure available to any Cloudflare developer. We didn’t build internal tools that aren’t available to you — instead we built it with the same Cloudflare lego blocks that you have access to.

Building Agent Lee on our own primitives wasn’t just a design principle. It was the fastest way to find out what works and what doesn’t. We built this in production, with real users, against real accounts. That means every limitation we hit is a limitation we can fix in the platform. Every pattern that works is one we can make easier for the next team that builds on top of it.

These are not opinions. They’re what quarter of a million tool calls across 18,000 users a day are telling us.


Generative UI

Interacting with a platform should feel like collaborating with an expert. Conversations should transcend simple text. With Agent Lee, as your dialogue evolves, the platform dynamically generates UI components alongside textual responses to provide a richer, more actionable experience.

For example, if you ask about website traffic trends for the month, you won’t just get a paragraph of numbers. Agent Lee will render an interactive line graph, allowing you to visualize peaks and troughs in activity at a glance.

To give you full creative control, every conversation is accompanied within an adaptive grid. Here you can click and drag across the grid to carve out space for new UI blocks, then simply describe what you want to see and let the agent handle the heavy lifting.

Today, we support a diverse library of visual blocks, including dynamic tables, interactive charts, architecture maps, and more. By blending the flexibility of natural language with the clarity of structured UI, Agent Lee transforms your chat history into a living dashboard.


Measuring quality and safety

An agent that can take action on your account needs to be reliable and secure. Elicitations allow agentic systems to actively solicit information, preferences, or approvals from users or other systems mid-execution. When Agent Lee needs to take non-read actions on a user’s behalf we use elicitations by requiring an explicit approval action in the user interface. These guardrails allow Agent Lee to truly be a partner alongside you in managing your resource safely.

In addition to safety, we continuously measure quality.

  • Evals to measure conversation success rate and information accuracy.

  • Feedback signals from user interactions (thumbs up / thumbs down).

  • Tool call execution success rate and hallucination scorers.

  • Per-product breakdown of conversation performance.

These systems help us improve Agent Lee over time while keeping users in control. 

Our vision ahead

Agent Lee in the dashboard is only the beginning.

The bigger vision is Agent Lee as the interface to the entire Cloudflare platform — from anywhere. The dashboard today, the CLI next, your phone when you’re on the go. The surface you use shouldn’t matter. You should be able to describe what you need and have it done, regardless of where you are.

From there, Agent Lee gets proactive. Rather than waiting to be asked, it watches what matters to you, your Workers, your traffic, your error thresholds and reaches out when something warrants attention. An agent that only responds is useful. One that notices things first is something different.

Underlying all of this is context. Agent Lee already knows your account configuration. Over time, it will know more, what you’ve asked before, what page you’re on, what you were debugging last week. That accumulated context is what makes a platform feel less like a tool and more like a collaborator.

We’re not there yet. Agent Lee today is the first step, running in production, doing real work at scale. The architecture is built to get to the rest.

Try it out

Agent Lee is available in beta for Free plan users. Log in to your Cloudflare dashboard and click Ask AI in the upper right corner to get started.


We’d love to know what you build and what you’d like to see in Agent Lee. Please share your feedback here.


Secure private networking for everyone: users, nodes, agents, Workers — introducing Cloudflare Mesh

Post Syndicated from Nikita Cano original https://blog.cloudflare.com/mesh/

AI agents have changed how teams think about private network access. Your coding agent needs to query a staging database. Your production agent needs to call an internal API. Your personal AI assistant needs to reach a service running on your home network. The clients are no longer just humans or services. They’re agents, running autonomously, making requests you didn’t explicitly approve, against infrastructure you need to keep secure.

Each of these workflows has the same underlying problem: agents need to reach private resources, but the tools for doing that were built for humans, not autonomous software. VPNs require interactive login. SSH tunnels require manual setup. Exposing services publicly is a security risk. And none of these approaches give you visibility into what the agent is actually doing once it’s connected.

Today, we’re introducing Cloudflare Mesh to connect your private networks together and provide secure access for your agents. We’re also integrating Mesh with Cloudflare Developer Platform so that Workers, Durable Objects, and agents built with the Agents SDK can reach your private infrastructure directly.

If you’re using Cloudflare One’s SASE and Zero Trust suite, you already have access to Mesh. You don’t need a new technology paradigm to secure agentic workloads. You need a SASE that was built for the agentic era, and that’s Cloudflare One. Cloudflare Mesh is a new experience with a simpler setup that leverages the on-ramps you’re already familiar with: WARP Connector (now called a Cloudflare Mesh node) and WARP Client (now called Cloudflare One Client). Together, these create a private network for human, developer, and agent traffic. Mesh is directly integrated into your existing Cloudflare One deployment. Your existing Gateway policies, Access rules, and device posture checks apply to Mesh traffic automatically.

If you’re a developer who just wants private networking for your agents, services, and team, Mesh is where you start. Set it up in minutes, connect your networks, and secure your traffic. And because Mesh runs on the Cloudflare One platform, you can grow into more advanced capabilities over time: Gateway network, DNS, and HTTP policies for fine-grained traffic control, Access for Infrastructure for SSH and RDP session management, Browser Isolation for safe web access, DLP to prevent sensitive data from leaving your network, and CASB for SaaS security. You won’t have to plan for all of this on day one. You just don’t have to migrate when you need it.

New agentic workflows

Private networking has always been about connecting clients to resources — SSH into a server, query a database, access an internal API. What’s changed is who the clients are. A year ago, the answer was your developers and your services. Today, it’s increasingly your agents.

This isn’t theoretical. Look at the ecosystem: the explosion of MCP (Model Context Protocol) servers providing tool access, coding agents that need to read from private repos and databases, personal assistants running on home hardware. Each of these patterns assumes the agent can reach the resources it needs. When those resources are isolated in private networks, the agent is stuck.


This creates three workflows that are hard to secure today:

  1. Accessing a personal agent from a mobile device. You’re running OpenClaw on a Mac mini at home. You want to reach it from your phone, your laptop at a coffee shop, or your work machine. But exposing it to the public Internet (even behind a password) can leave some gaps exposed. Your agent has shell access, file system access, and network access to your home network. One misconfiguration and anyone can reach it.

  2. Letting a coding agent access your staging environment. You’re using Claude Code, Cursor, or Codex on your laptop. You ask it to check deployment status, query analytics from a staging database, or read from an internal object store. But those services live in a private cloud VPC, so your agent can’t reach them without exposing them to the Internet or tunneling your entire laptop into the VPC.

  3. Connecting deployed agents to private services. You’re building agents into your product using the Agents SDK on Cloudflare Workers. Those agents need to call internal APIs, query databases, and access services that aren’t on the public Internet. They need private access, but with scoped permissions, audit trails, and no credential leakage.

Cloudflare Mesh: one private network for users, nodes, and agents

Cloudflare Mesh is developer-friendly private networking. One lightweight connector, one binary, connects everything: your personal devices, your remote servers, your user endpoints. You don’t need to install separate tools for each pattern. One connector on your network, and every access pattern works.

Once connected, devices in your private network can talk to each other over private IPs, routed through Cloudflare’s global network across 330+ cities giving you better reliability and control over your network.


Now, with Mesh, a single solution can solve all of the agent scenarios we mentioned above:

  • With Cloudflare One Client for iOS on your phone, you can securely connect your mobile devices to your local Mac mini running OpenClaw via a Mesh private network.

  • With Cloudflare One Client for macOS on your laptop, you can connect your laptop to your private network so your coding agents can reach staging databases or APIs and query them.

  • With Mesh nodes on your Linux servers, you can connect VPCs in external clouds together, letting agents access resources and MCPs in external private networks.

Because Mesh is powered by Cloudflare One Client, every connection inherits the security controls of the Cloudflare One platform. Gateway policies apply to Mesh traffic. Device posture checks validate connecting devices. DNS filtering catches suspicious lookups. You get this without additional configuration: the same policies that protect your human traffic protect your agent traffic.

Choosing between Mesh and Tunnel

With the introduction of Mesh, you might ask: when should I use Mesh instead of Tunnel? Both connect external networks privately to Cloudflare, but they serve different purposes. Cloudflare Tunnel is the ideal solution for unidirectional traffic, where Cloudflare proxies the traffic from the edge to specific private services (like a web server or a database). 

Cloudflare Mesh, on the other hand, provides a full bidirectional, many-to-many network. Every device and node on your Mesh can access one another using their private IPs. An application or agent running in your network can discover and access any other resource on the Mesh without each resource needing its own Tunnel. 

Using the power of Cloudflare’s network

Cloudflare Mesh gives you the benefits of a mesh network (resiliency, high scalability, low latency and high performance), but, by routing everything through Cloudflare, it resolves a key challenge of mesh networks: NAT traversal.

Most of the Internet is behind NAT (Network Address Translation). This mechanism allows an entire local network of devices to share a single public IP address by mapping traffic between public headers and private internal addresses. When two devices are behind NAT, direct connections can fail and traffic has to fall back to relay servers. If your relay infrastructure has limited points of presence, a meaningful fraction of your traffic hits those relays, adding latency and reducing reliability. And while it can be possible to self-host your own relay servers to compensate, that means taking on the burden of managing additional infrastructure just to connect your existing network.

Cloudflare Mesh takes a different approach. All Mesh traffic routes through Cloudflare’s global network, the same infrastructure that serves traffic for some of the largest websites of the Internet. For cross-region or multi-cloud traffic, this consistently beats public Internet routing. There’s no degraded fallback path, because the Cloudflare edge is the path.

Routing through Cloudflare also means every packet passes through Cloudflare’s security stack. This is the key advantage of building Mesh on the Cloudflare One platform: security isn’t a separate product you bolt on later. And by leveraging this same global backbone, we can provide these core pillars to every team from day one:

50 nodes and 50 users free. Your whole team and your whole staging environment on one private network, included with every Cloudflare account. 

Global edge routing. 330+ cities, optimized backbone routing. No relay servers with limited points of presence. No degraded fallback paths.

Security controls from day one. Mesh runs on Cloudflare One. Gateway policies, DNS filtering, DLP, traffic inspection, and device posture checks are all available on the same platform. Start with simple private connectivity. Turn on Gateway policies when you need traffic filtering. Enable Access for Infrastructure when you need session-level controls for SSH and RDP. Add DLP when you need to prevent sensitive data from leaving your network. Every capability is one toggle away.

High availability. Create a Mesh node with high availability enabled and spin up multiple connectors using the same token in active-passive mode. They advertise the same IP routes, so if one goes down, traffic fails over automatically.

Integrated with the Developer Platform with Workers VPC

Mesh connects your agents and resources across external clouds, but you also need to be able to connect from your agents built on Workers with Agents SDK as well. To enable this, we’ve extended Workers VPC to make your entire Mesh network accessible to Workers and Durable Objects.

That means that you can connect to your Cloudflare Mesh network from Workers, making the entire network accessible from a single binding’s fetch() call. This complements Workers VPC’s existing support for Cloudflare Tunnel, giving you more choice over how you want to secure your networks. Now, you can specify entire networks that you want to connect to in your wrangler.jsonc file. To bind to your Mesh network, use the cf1:network reserved keyword that binds to the Mesh network of your account:

"vpc_networks": [
  { "binding": "MESH", "network_id": "cf1:network", "remote": true },
  { "binding": "AWS_VPC", "tunnel_id": "350fd307-...", "remote": true }
]

Then, you can use it within your Worker or agent code:

export default {
  async fetch(request: Request, env: Env, ctx: ExecutionContext) {
    // Reach any internal host on your Mesh, no pre-registration required
    const apiResponse = await env.MESH.fetch("http://10.0.1.50/api/data");

    // Internal hostname resolved via tunnel's private DNS resolver
    const dbResponse = await env.AWS_VPC.fetch("http://internal-db.corp.local:5432");

    return new Response(await apiResponse.text());
  },
};

By connecting the Developer Platform to your Mesh networks, you can build Workers that have secure access to your private databases, internal APIs and MCPs, allowing you to build cross-cloud agents and MCPs that provide agentic capabilities to your app. But it also opens up a world where agents can autonomously observe your entire stack end-to-end, cross-reference logs and suggest optimizations in real-time.

How it all fits together

Together, Cloudflare Mesh, Workers VPC, and the Agents SDK provide a unified private network for your agents that spans both Cloudflare and your external clouds. We’ve merged connectivity and compute so your agents can securely reach the resources they need, wherever they live, across the globe.


Mesh nodes are your servers, VMs, and containers. They run a headless version of Cloudflare One Client and get a Mesh IP. Services talk to services over private IPs, bidirectionally, routed through Cloudflare’s edge. 

Devices are your laptops and phones. They run the Cloudflare One Client and reach Mesh nodes directly: SSH, database queries, API calls, all over private IPs. Your local coding agents use this connection to access private resources. 

Agents on Workers reach private services through Workers VPC Network bindings. They get scoped access to entire networks, mediated by MCP. The network enforces what the agent can reach. The MCP server enforces what the agent can do. 

What’s next

The current version of Mesh provides the foundation for secure, unified connectivity. But as agentic workflows become more complex, we’re focused on moving beyond simple connectivity toward a network that is more intuitive to manage and more granularly aware of who, or what, is talking to your services. Here is what we are building for the rest of the year.

Hostname routing

We’re extending Cloudflare Tunnel’s hostname routing to Mesh this summer. Your Mesh nodes will be able to attract traffic for private hostnames like wiki.local or api.staging.internal, without you having to manage IP lists or worry about how those hostnames resolve on the Cloudflare edge. Route traffic to services by name, not by IP. If your infrastructure uses dynamic IPs, auto-scaling groups, or ephemeral containers, this removes an entire class of routing headaches.

Mesh DNS

Today, you reach Mesh nodes by their Mesh IPs: ssh 100.64.0.5. That works, but it’s not how you think about your infrastructure. You think in names: postgres-staging, api-prod, nikitas-openclaw.

Later this year we’re building Mesh DNS so that every node and device that joins your Mesh automatically gets a routable internal hostname. No DNS configuration or manual records. Add a node named postgres-staging, and postgres-staging.mesh resolves to the right Mesh IP from any device on your Mesh.

Combined with hostname routing, you’ll be able to ssh postgres-staging.mesh or curl http://api-prod.mesh:3000/health without ever knowing or managing an IP address.

Identity-aware routing

Today, Mesh nodes authenticate to the Cloudflare edge, but they share an identity at the network layer. Devices authenticate with user identity via the Cloudflare One Client, but nodes don’t yet carry distinct, routable identities that Gateway policies can differentiate.

We want to change that. The goal is identity-aware routing for Mesh, where each node, each device, and eventually each agent gets a distinct identity that policies can evaluate. Instead of writing rules based on IP ranges, you write rules based on who or what is connecting.

This matters most for agents. Today, when an agent running on Workers calls a tool through a VPC binding, the target service sees a Worker making a request. It doesn’t know which agent is calling, who authorized it, or what scope was granted. On the Mesh side, when a local coding agent on your laptop reaches a staging service, Gateway sees your device identity but not the agent’s.

We’re working toward a model where agents carry their own identity through the network:

  • Principal / Sponsor: The human who authorized the action (Nikita from the platform team)

  • Agent: The AI system performing it (the deployment assistant, session #abc123)

  • Scope: What the agent is allowed to do (read deployments, trigger rollbacks, nothing else)

This would let you write policies like: reads from Nikita’s agents are allowed, but writes require Nikita directly. Agent traffic can be filtered independently from human traffic. An agent’s network access can be revoked without touching Nikita’s.

The infrastructure for this is in place. Mesh nodes provision with per-node tokens, devices authenticate with per-user identity, and Workers VPC bindings scope per-service access. The missing piece is making these identities visible to the policy layer so Gateway can make routing and access decisions based on them. That’s what we’re building.

Mesh in containers

Today, Mesh nodes run on VMs and bare-metal Linux servers. But modern infrastructure increasingly runs in containers: Kubernetes pods, Docker Compose stacks, ephemeral CI/CD runners. We’re building a Mesh Docker image that lets you add a Mesh node to any containerized environment.

This means you’ll be able to include a Mesh sidecar in your Docker Compose stack and give every service in that stack private network access. A microservice running in a container in your staging cluster could reach a database in your production VPC over Mesh, without either service needing a public endpoint.

It is also useful for CI/CD pipelines that can access private infrastructure during builds and tests: your GitHub Actions runner pulls the Mesh container image, joins your network, runs integration tests against your staging environment, and tears down. All without VPN credentials to manage or persistent tunnels to maintain: the node disappears when the container exits.

We expect the Mesh Docker image to be available later this year.

Get started

While we continue to evolve these identity and routing capabilities, the foundation for secure, unified networking is available today. You can start bridging your clouds and securing your agents in just a few minutes.

Get started Cloudflare Mesh: Head to Networking > Mesh in the Cloudflare dashboard. Free for up to 50 nodes and 50 users.

Build agents with Agents SDK and Workers VPC: Install the Agents SDK (`npm i agents`), follow the Workers VPC quickstart, and build a remote MCP server with private backend access.

Already on Cloudflare One? Mesh works with your existing setup. Your Gateway policies, device posture checks, and access rules apply to Mesh traffic automatically. See the Mesh documentation to add your first node.


Watch on Cloudflare TV

Welcome to Agents Week

Post Syndicated from Rita Kozlov original https://blog.cloudflare.com/welcome-to-agents-week/

Cloudflare’s mission has always been to help build a better Internet. Sometimes that means building for the Internet as it exists. Sometimes it means building for the Internet as it’s about to become. 

Today, we’re kicking off Agents Week, dedicated to building the Internet for what comes next.

The Internet wasn’t built for the age of AI. Neither was the cloud.

The cloud, as we know it, was a product of the last major technological paradigm shift: smartphones.

When smartphones put the Internet in everyone’s pocket, they didn’t just add users — they changed the nature of what it meant to be online. Always connected, always expecting an instant response. Applications had to handle an order of magnitude more users, and the infrastructure powering them had to evolve.

The approach the industry converged on was straightforward: more users, more copies of your application. As applications grew in complexity, teams broke them into smaller pieces — microservices — so each team could control its own destiny. But the core principle stayed the same: a finite number of applications, each serving many users. Scale meant more copies.

Kubernetes and containers became the default. They made it easy to spin up instances, load balance, and tear down what you didn’t need. Under this one-to-many model, a single instance could serve many users, and even as user counts grew into the billions, the number of things you had to manage stayed finite.

Agents break this.

One user, one agent, one task

Unlike every application that came before them, agents are one-to-one. Each agent is a unique instance. Serving one user, running one task. Where a traditional application follows the same execution path regardless of who’s using it, an agent requires its own execution environment: one where the LLM dictates the code path, calls tools dynamically, adjusts its approach, and persists until the task is done.

Think of it as the difference between a restaurant and a personal chef. A restaurant has a menu — a fixed set of options — and a kitchen optimized to churn them out at volume. That’s most applications today. An agent is more like a personal chef who asks: what do you want to eat? They might need entirely different ingredients, utensils, or techniques each time. You can’t run a personal-chef service out of the same kitchen setup you’d use for a restaurant.

Over the past year, we’ve seen agents take off, with coding agents leading the way — not surprisingly, since developers tend to be early adopters. The way most coding agents work today is by spinning up a container to give the LLM what it needs: a filesystem, git, bash, and the ability to run arbitrary binaries.

But coding agents are just the beginning. Tools like Claude Cowork are already making agents accessible to less technical users. Once agents move beyond developers and into the hands of everyone — administrative assistants, research analysts, customer service reps, personal planners — the scale math gets sobering fast.

The math on scaling agents to the masses

If the more than 100 million knowledge workers in the US each used an agentic assistant at ~15% concurrency, you’d need capacity for approximately 24 million simultaneous sessions. At 25–50 users per CPU, that’s somewhere between 500K and 1M server CPUs — just for the US, with one agent per person.

Now picture each person running several agents in parallel. Now picture the rest of the world with more than 1 billion knowledge workers. We’re not a little short on compute. We’re orders of magnitude away.

So how do we close that gap?

Infrastructure built for agents

Eight years ago, we launched Workers — the beginning of our developer platform, and a bet on containerless, serverless compute. The motivation at the time was practical: we needed lightweight compute without cold-starts for customers who depended on Cloudflare for speed. Built on V8 isolates rather than containers, Workers turned out to be an order of magnitude more efficient — faster to start, cheaper to run, and natively suited to the “spin up, execute, tear down” pattern.

What we didn’t anticipate was how well this model would map to the age of agents.

Where containers give every agent a full commercial kitchen: bolted-down appliances, walk-in fridges, the works, whether the agent needs them or not, isolates, on the other hand, give the personal chef exactly the counter space, the burner, and the knife they need for this particular meal. Provisioned in milliseconds. Cleaned up the moment the dish is served.


In a world where we need to support not thousands of long-running applications, but billions of ephemeral, single-purpose execution environments — isolates are the right primitive. 

Each one starts in milliseconds. Each one is securely sandboxed. And you can run orders of magnitude more of them on the same hardware compared to containers.

Just a few weeks ago, we took this further with the Dynamic Workers open beta: execution environments spun up at runtime, on demand. An isolate takes a few milliseconds to start and uses a few megabytes of memory. That’s roughly 100x faster and up to 100x more memory-efficient than a container. 

You can start a new one for every single request, run a snippet of code, and throw it away — at a scale of millions per second.

For agents to move beyond early adopters and into everyone’s hands, they also have to be affordable. Running each agent in its own container is expensive enough that agentic tools today are mostly limited to coding assistants for engineers who can justify the cost. Isolates, by running orders of magnitude more efficiently, are what make per-unit economics viable at the scale agents require.


The horseless carriage phase

While it’s critical to build the right foundation for the future, we’re not there yet. And every paradigm shift has a period where we try to make the new thing work within the old model. The first cars were called “horseless carriages.” The first websites were digital brochures. The first mobile apps were shrunken desktop UIs. We’re in that phase now with agents.

You can see it everywhere. 

We’re giving agents headless browsers to navigate websites designed for human eyes, when what they need are structured protocols like MCP to discover and invoke services directly. 

Many early MCP servers are thin wrappers around existing REST APIs — same CRUD operations, new protocol — when LLMs are actually far better at writing code than making sequential tool calls. 

We’re using CAPTCHAs and behavioral fingerprinting to verify the thing on the other end of a request, when increasingly that thing is an agent acting on someone’s behalf — and the right question isn’t “are you human?” but “which agent are you, who authorized you, and what are you allowed to do?”

We’re spinning up full containers for agents that just need to make a few API calls and return a result.

These are just a few examples, but none of this is surprising. It’s what transitions look like.

Building for both

The Internet is always somewhere between two eras. IPv6 is objectively better than IPv4, but dropping IPv4 support would break half the Internet. HTTP/2 and HTTP/3 coexist. TLS 1.2 still hasn’t fully given way to 1.3. The better technology exists, the old technology persists, and the job of infrastructure is to bridge both.

Cloudflare has always been in the business of bridging these transitions. The shift to agents is no different.

Coding agents genuinely need containers — a filesystem, git, bash, arbitrary binary execution. That’s not going away. This week, our container-based sandbox environments are going GA, because we’re committed to making them the best they can be. We’re going deeper on browser rendering for agents, because there will be a long tail of services that don’t yet speak MCP, and agents will still need to interact with them. These aren’t stopgaps — they’re part of a complete platform.

But we’re also building what comes next: the isolates, the protocols, and the identity models that agents actually need. Our job is to make sure you don’t have to choose between what works today and what’s right for tomorrow.

Security in the model, not around it

If agents are going to handle our professional and personal tasks — reading our email, operating on our code, interacting with our financial services — then security has to be built into the execution model, not layered on after the fact.

CISOs have been the first to confront this. The productivity gains from putting agents in everyone’s hands are real, but today, most agent deployments are fraught with risk: prompt injection, data exfiltration, unauthorized API access, opaque tool usage. 

A developer’s vibe-coding agent needs access to repositories and deployment pipelines. An enterprise’s customer service agent needs access to internal APIs and user data. In both cases, securing the environment today means stitching together credentials, network policies, and access controls that were never designed for autonomous software.

Cloudflare has been building two platforms in parallel: our developer platform, for people who build applications, and our zero trust platform, for organizations that need to secure access. For a while, these served distinct audiences. 

But “how do I build this agent?” and “how do I make sure it’s safe?” are increasingly the same question. We’re bringing these platforms together so that all of this is native to how agents run, not a separate layer you bolt on.

Agents that follow the rules

There’s another dimension to the agent era that goes beyond compute and security: economics and governance.

When agents interact with the Internet on our behalf — reading articles, consuming APIs, accessing services — there needs to be a way for the people and organizations who create that content and run those services to set terms and get paid. Today, the web’s economic model is built around human attention: ads, paywalls, subscriptions. 

Agents don’t have attention (well, not that kind of attention). They don’t see ads. They don’t click through cookie banners.

If we want an Internet where agents can operate freely and where publishers, content creators, and service providers are fairly compensated, we need new infrastructure for it. We’re building tools that make it easy for publishers and content owners to set and enforce policies for how agents interact with their content.

Building a better Internet has always meant making sure it works for everyone — not just the people building the technology, but the people whose work and creativity make the Internet worth using. That doesn’t change in the age of agents. It becomes more important.

The platform for developers and agents

Our vision for the developer platform has always been to provide a comprehensive platform that just works: from experiment, to MVP, to scaling to millions of users. But providing the primitives is only part of the equation. A great platform also has to think about how everything works together, and how it integrates into your development flow.

That job is evolving. It used to be purely about developer experience, making it easy for humans to build, test, and ship. Increasingly, it’s also about helping agents help humans, and making the platform work not just for the people building agents, but for the agents themselves. Can an agent find the latest most up-to- date best practices? How easily can it discover and invoke the tools and CLIs it needs? How seamlessly can it move from writing code to deploying it?

This week, we’re shipping improvements across both dimensions — making Cloudflare better for the humans building on it and for the agents running on it.

Building for the future is a team sport

Building for the future is not something we can do alone. Every major Internet transition from HTTP/1.1 to HTTP/2 and HTTP/3, from TLS 1.2 to 1.3 — has required the industry to converge on shared standards. The shift to agents will be no different.

Cloudflare has a long history of contributing to and helping push forward the standards that make the Internet work. We’ve been deeply involved in the IETF for over a decade, helping develop and deploy protocols like QUIC, TLS 1.3, and Encrypted Client Hello. We were a founding member of WinterTC, the ECMA technical committee for JavaScript runtime interoperability. We open-sourced the Workers runtime itself, because we believe the foundation should be open.

We’re bringing the same approach to the agentic era. We’re excited to be part of the Linux Foundation and AAIF, and to help support and push forward standards like MCP that will be foundational for the agentic future. Since Anthropic introduced MCP, we’ve worked closely with them to build the infrastructure for remote MCP servers, open-sourced our own implementations, and invested in making the protocol practical at scale. 

Last year, alongside Coinbase, we co-founded the x402 Foundation, an open, neutral standard that revives the long-dormant HTTP 402 status code to give agents a native way to pay for the services and content they consume. 

Agent identity, authorization, payment, safety: these all need open standards that no single company can define alone.

Stay tuned

This week, we’re making announcements across every dimension of the agent stack: compute, connectivity, security, identity, economics, and developer experience.

The Internet wasn’t built for AI. The cloud wasn’t built for agents. But Cloudflare has always been about helping build a better Internet — and what “better” means changes with each era. This is the era of agents. This week, follow along and we’ll show you what we’re building for it.

500 Tbps of capacity: 16 years of scaling our global network

Post Syndicated from Tanner Ryan original https://blog.cloudflare.com/500-tbps-of-capacity/

Cloudflare’s global network and backbone in 2026.

Cloudflare’s network recently passed a major milestone: we crossed 500 terabits per second (Tbps) of external capacity.

When we say 500 Tbps, we mean total provisioned external interconnection capacity: the sum of every port facing a transit provider, private peering partner, Internet exchange, or Cloudflare Network Interconnect (CNI) port across all 330+ cities. This is not peak traffic. On any given day, our peak utilization is a fraction of that number. (The rest is our DDoS budget.)

It’s a long way from where we started. In 2010, we launched from a small office above a nail salon in Palo Alto, with a single transit provider and a reverse proxy you could set up by changing two nameservers.

The early days of transit and peering

Our first transit provider was nLayer Communications, a network most people now know as GTT. nLayer gave us our first capacity and our first hands-on company experience in peering relationships and the careful balance between cost and performance.

From there, we grew city by city: Chicago, Ashburn, San Jose, Amsterdam, Tokyo. Each new data center meant negotiating colocation contracts, pulling fiber, racking servers, and establishing peering through Internet exchanges. The Internet isn’t actually a cloud, of course. It is a collection of specific rooms full of cables, and we spent years learning the nuances of every one of them.

Not every city was a straightforward deployment, having to deal with missing hardware, customs strikes, and even dental floss. In a single month in 2018, we opened up in 31 cities in 24 days: from Kathmandu and Baghdad to Reykjavík and Chișinău. When we opened our 127th data center in Macau, we were protecting 7 million Internet properties. Today, with data centers in 330+ cities, we protect more than 20% of the web.

When the network became the security layer 

As our footprint grew, customers asked for more than just website caching. They needed to protect employees, replace aging Multiprotocol Label Switching (MPLS) circuits, and secure entire enterprise networks. Instead of traditional appliances, we built systems to establish secure tunnels to private subnets and advertise enterprise IP space directly from our global network via BGP.

The scale of threats grew in parallel. In 2025, we mitigated a 31.4 Tbps DDoS attack lasting 35 seconds. The source was the Aisuru-Kimwolf botnet, including many infected Android TVs. It was one of over 5,000 attacks we blocked that day. No engineer was paged.


A decade ago, an attack of that magnitude would have required nation-state resources to counter. Today, our network handles it in seconds without human intervention. That is what operating at a 500 Tbps scale requires: moving the intelligence to every server in our network so the network can defend itself.

How our network responds to an attack

Here is what actually happens when an attack hits our network. Packets arrive at the network interface card (NIC) and immediately enter an eXpress Data Path (XDP) program chain managed by xdpd, running in driver mode. Among the first programs in that chain is l4drop, which evaluates each packet against mitigation rules in extended Berkeley Packet Filter (eBPF). Those rules are generated by dosd, our denial of service daemon, which runs on every server in our fleet. Each dosd instance samples incoming traffic, builds a table of the heaviest hitters it sees, and broadcasts that table to every other instance in the colo. The result is a shared colo-wide view of traffic, and because every server works from the same data, they reach the same mitigation decision.


When dosd detects an attack pattern, the resulting rule is applied locally via l4drop and propagates globally via Quicksilver, our distributed key-value (KV) store, reaching every server in every data center within seconds. Only after surviving l4drop do packets reach Unimog, our Layer 4 (L4) load balancer, which distributes them across healthy servers in the data center. For Magic Transit customers routing enterprise network traffic through our edge, flowtrackd adds a further layer of stateful TCP inspection, tracking connection state and dropping packets that don’t belong to legitimate flows.

The 31.4 Tbps attack we mitigated followed exactly this path. No traffic was backhauled to a centralized scrubbing center. No human intervened. Every server in the targeted data centers independently recognized the attack and began dropping malicious packets at line rate, before those packets consumed a single CPU cycle of application processing. The software is only half the story: none of it works if the ports aren’t there to absorb the traffic in the first place.

A distributed developer platform

Running code on every server in our network was a natural consequence of controlling the full stack. If we already ran eBPF programs on every machine to drop attack traffic, we could run customer application code there too. That insight became Workers, and later KV and Durable Objects.

Our developer platform runs in every city we operate in, not in a handful of cloud regions. In 2025, we added Containers to Workers, so heavier workloads can run at the edge too. V8 isolates and custom filesystem layers minimize cold starts. Your code runs where your users are, on the same servers that drop attack traffic at line rate via l4drop. Attack traffic is dropped before it reaches the network stack. Your application never sees it.

Forward-looking protocols: IPv6, RPKI, ASPA

We were early adopters of IPv6 and Resource Public Key Infrastructure (RPKI). BGP hijacks cause real outages and security breaches. RPKI allows us to drop invalid routes from peers, ensuring traffic goes where it is supposed to. We sign Route Origin Authorizations (ROAs) for our prefixes and enforce Route Origin Validation on ingress. We reject RPKI-invalid routes, even when that occasionally breaks reachability to networks with misconfigured ROAs.

Autonomous System Provider Authorization (ASPA) is next. RPKI validates who owns a prefix. ASPA validates the path it took to get here. RPKI is a passport check at the destination, confirming the right owner, while ASPA is a flight manifest check: it verifies every network the traffic passed through. A route leak is like a passenger who boarded in the wrong city; RPKI would not catch it, but ASPA will.

Current ecosystem adoption for ASPA looks like RPKI did in 2015. We were one of the first networks to deploy RPKI at scale, and today, 867,000 prefixes in the global routing table have valid RPKI certificates, up from near zero a decade ago. At our scale, the protocols we choose have real consequences for the broader Internet. We push for adoption early because waiting means more hijacks and more leaks in the meantime.

AI agents and the evolving Internet

AI has changed what it means to have a presence on the web. For most of the Internet’s history, traffic was human-generated, by people clicking links in browsers. Today, AI crawlers, model training pipelines, and autonomous agents now account for more than 4% of all HTML requests across our network, comparable to Googlebot itself. “User action” crawling, where an AI visits a page because a human asked it a question, grew over 15x in 2025 alone.

AI crawlers behave differently than browsers at the infrastructure level. Browsers load a page and stop. Crawlers instead fetch every linked resource at maximum throughput with no pause between requests. At our scale, distinguishing legitimate AI crawling from actual attacks is a real engineering problem. Our detection systems use a combination of verified bot IP ranges, TLS fingerprinting, behavioral analysis, and robots.txt compliance signals to make that distinction, and to give site owners the data they need to decide which crawlers to allow.

At the TLS layer, for example, a legitimate browser presents a ClientHello with a predictable set of cipher suites, extensions, and ordering that matches its declared User-Agent. A crawler spoofing that User-Agent but using a stripped-down TLS library will present a different fingerprint, and that mismatch is one of the signals our systems use to classify the request before it reaches the origin.

Help us build the next 500 Tbps

What started above a nail salon in Palo Alto is now a 500 Tbps network in 330+ cities across 125+ countries, where every server runs our developer platform and security services, not just cache. That is sixteen years of architectural decisions compounding, and we owe it to the 13,000+ networks and partners who peer with us. We are not done.

If you are a network operator, peer with us. Our peering policy and interconnection details are on PeeringDB. If you are interested in embedding Cloudflare infrastructure directly within your network, reach out to our team at [email protected], to join the Edge Partner Program.

Sandboxing AI agents, 100x faster

Post Syndicated from Kenton Varda original https://blog.cloudflare.com/dynamic-workers/

Last September we introduced Code Mode, the idea that agents should perform tasks not by making tool calls, but instead by writing code that calls APIs. We’ve shown that simply converting an MCP server into a TypeScript API can cut token usage by 81%. We demonstrated that Code Mode can also operate behind an MCP server instead of in front of it, creating the new Cloudflare MCP server that exposes the entire Cloudflare API with just two tools and under 1,000 tokens.

But if an agent (or an MCP server) is going to execute code generated on-the-fly by AI to perform tasks, that code needs to run somewhere, and that somewhere needs to be secure. You can’t just eval() AI-generated code directly in your app: a malicious user could trivially prompt the AI to inject vulnerabilities.

You need a sandbox: a place to execute code that is isolated from your application and from the rest of the world, except for the specific capabilities the code is meant to access.

Sandboxing is a hot topic in the AI industry. For this task, most people are reaching for containers. Using a Linux-based container, you can start up any sort of code execution environment you want. Cloudflare even offers our container runtime and our Sandbox SDK for this purpose.

But containers are expensive and slow to start, taking hundreds of milliseconds to boot and hundreds of megabytes of memory to run. You probably need to keep them warm to avoid delays, and you may be tempted to reuse existing containers for multiple tasks, compromising the security.

If we want to support consumer-scale agents, where every end user has an agent (or many!) and every agent writes code, containers are not enough. We need something lighter.

And we have it.

Dynamic Worker Loader: a lean sandbox

Tucked into our Code Mode post in September was the announcement of a new, experimental feature: the Dynamic Worker Loader API. This API allows a Cloudflare Worker to instantiate a new Worker, in its own sandbox, with code specified at runtime, all on the fly.

Dynamic Worker Loader is now in open beta, available to all paid Workers users.

Read the docs for full details, but here’s what it looks like:

// Have your LLM generate code like this.
let agentCode: string = `
  export default {
    async myAgent(param, env, ctx) {
      // ...
    }
  }
`;

// Get RPC stubs representing APIs the agent should be able
// to access. (This can be any Workers RPC API you define.)
let chatRoomRpcStub = ...;

// Load a worker to run the code, using the worker loader
// binding.
let worker = env.LOADER.load({
  // Specify the code.
  compatibilityDate: "2026-03-01",
  mainModule: "agent.js",
  modules: { "agent.js": agentCode },

  // Give agent access to the chat room API.
  env: { CHAT_ROOM: chatRoomRpcStub },

  // Block internet access. (You can also intercept it.)
  globalOutbound: null,
});

// Call RPC methods exported by the agent code.
await worker.getEntrypoint().myAgent(param);

That’s it.

100x faster

Dynamic Workers use the same underlying sandboxing mechanism that the entire Cloudflare Workers platform has been built on since its launch, eight years ago: isolates. An isolate is an instance of the V8 JavaScript execution engine, the same engine used by Google Chrome. They are how Workers work.

An isolate takes a few milliseconds to start and uses a few megabytes of memory. That’s around 100x faster and 10x-100x more memory efficient than a typical container.

That means that if you want to start a new isolate for every user request, on-demand, to run one snippet of code, then throw it away, you can.

Unlimited scalability

Many container-based sandbox providers impose limits on global concurrent sandboxes and rate of sandbox creation. Dynamic Worker Loader has no such limits. It doesn’t need to, because it is simply an API to the same technology that has powered our platform all along, which has always allowed Workers to seamlessly scale to millions of requests per second.

Want to handle a million requests per second, where every single request loads a separate Dynamic Worker sandbox, all running concurrently? No problem!

Zero latency

One-off Dynamic Workers usually run on the same machine — the same thread, even — as the Worker that created them. No need to communicate around the world to find a warm sandbox. Isolates are so lightweight that we can just run them wherever the request landed. Dynamic Workers are supported in every one of Cloudflare’s hundreds of locations around the world.

It’s all JavaScript

The only catch, vs. containers, is that your agent needs to write JavaScript.

Technically, Workers (including dynamic ones) can use Python and WebAssembly, but for small snippets of code — like that written on-demand by an agent — JavaScript will load and run much faster.

We humans tend to have strong preferences on programming languages, and while many love JavaScript, others might prefer Python, Rust, or countless others.

But we aren’t talking about humans here. We’re talking about AI. AI will write any language you want it to. LLMs are experts in every major language. Their training data in JavaScript is immense.

JavaScript, by its nature on the web, is designed to be sandboxed. It is the correct language for the job.

Tools defined in TypeScript

If we want our agent to be able to do anything useful, it needs to talk to external APIs. How do we tell it about the APIs it has access to?

MCP defines schemas for flat tool calls, but not programming APIs. OpenAPI offers a way to express REST APIs, but it is verbose, both in the schema itself and the code you’d have to write to call it.

For APIs exposed to JavaScript, there is a single, obvious answer: TypeScript.

Agents know TypeScript. TypeScript is designed to be concise. With very few tokens, you can give your agent a precise understanding of your API.

// Interface to interact with a chat room.
interface ChatRoom {
  // Get the last `limit` messages of the chat log.
  getHistory(limit: number): Promise<Message[]>;

  // Subscribe to new messages. Dispose the returned object
  // to unsubscribe.
  subscribe(callback: (msg: Message) => void): Promise<Disposable>;

  // Post a message to chat.
  post(text: string): Promise<void>;
}

type Message = {
  author: string;
  time: Date;
  text: string;
}

Compare this with the equivalent OpenAPI spec (which is so long you have to scroll to see it all):

openapi: 3.1.0
info:
  title: ChatRoom API
  description: >
    Interface to interact with a chat room.
  version: 1.0.0

paths:
  /messages:
    get:
      operationId: getHistory
      summary: Get recent chat history
      description: Returns the last `limit` messages from the chat log, newest first.
      parameters:
        - name: limit
          in: query
          required: true
          schema:
            type: integer
            minimum: 1
      responses:
        "200":
          description: A list of messages.
          content:
            application/json:
              schema:
                type: array
                items:
                  $ref: "#/components/schemas/Message"

    post:
      operationId: postMessage
      summary: Post a message to the chat room
      requestBody:
        required: true
        content:
          application/json:
            schema:
              type: object
              required:
                - text
              properties:
                text:
                  type: string
      responses:
        "204":
          description: Message posted successfully.

  /messages/stream:
    get:
      operationId: subscribeMessages
      summary: Subscribe to new messages via SSE
      description: >
        Opens a Server-Sent Events stream. Each event carries a JSON-encoded
        Message object. The client unsubscribes by closing the connection.
      responses:
        "200":
          description: An SSE stream of new messages.
          content:
            text/event-stream:
              schema:
                description: >
                  Each SSE `data` field contains a JSON-encoded Message object.
                $ref: "#/components/schemas/Message"

components:
  schemas:
    Message:
      type: object
      required:
        - author
        - time
        - text
      properties:
        author:
          type: string
        time:
          type: string
          format: date-time
        text:
          type: string

We think the TypeScript API is better. It’s fewer tokens and much easier to understand (for both agents and humans).

Dynamic Worker Loader makes it easy to implement a TypeScript API like this in your own Worker and then pass it in to the Dynamic Worker either as a method parameter or in the env object. The Workers Runtime will automatically set up a Cap’n Web RPC bridge between the sandbox and your harness code, so that the agent can invoke your API across the security boundary without ever realizing that it isn’t using a local library.

That means your agent can write code like this:

// Thinking: The user asked me to summarize recent chat messages from Alice.
// I will filter the recent message history in code so that I only have to
// read the relevant messages.
let history = await env.CHAT_ROOM.getHistory(1000);
return history.filter(msg => msg.author == "alice");

HTTP filtering and credential injection

If you prefer to give your agents HTTP APIs, that’s fully supported. Using the globalOutbound option to the worker loader API, you can register a callback to be invoked on every HTTP request, in which you can inspect the request, rewrite it, inject auth keys, respond to it directly, block it, or anything else you might like.

For example, you can use this to implement credential injection (token injection): When the agent makes an HTTP request to a service that requires authorization, you add credentials to the request on the way out. This way, the agent itself never knows the secret credentials, and therefore cannot leak them.

Using a plain HTTP interface may be desirable when an agent is talking to a well-known API that is in its training set, or when you want your agent to use a library that is built on a REST API (the library can run inside the agent’s sandbox).

With that said, in the absence of a compatibility requirement, TypeScript RPC interfaces are better than HTTP:

  • As shown above, a TypeScript interface requires far fewer tokens to describe than an HTTP interface.

  • The agent can write code to call TypeScript interfaces using far fewer tokens than equivalent HTTP.

  • With TypeScript interfaces, since you are defining your own wrapper interface anyway, it is easier to narrow the interface to expose exactly the capabilities that you want to provide to your agent, both for simplicity and security. With HTTP, you are more likely implementing filtering of requests made against some existing API. This is hard, because your proxy must fully interpret the meaning of every API call in order to properly decide whether to allow it, and HTTP requests are complicated, with many headers and other parameters that could all be meaningful. It ends up being easier to just write a TypeScript wrapper that only implements the functions you want to allow.

Battle-hardened security

Hardening an isolate-based sandbox is tricky, as it is a more complicated attack surface than hardware virtual machines. Although all sandboxing mechanisms have bugs, security bugs in V8 are more common than security bugs in typical hypervisors. When using isolates to sandbox possibly-malicious code, it’s important to have additional layers of defense-in-depth. Google Chrome, for example, implemented strict process isolation for this reason, but it is not the only possible solution.

We have nearly a decade of experience securing our isolate-based platform. Our systems automatically deploy V8 security patches to production within hours — faster than Chrome itself. Our security architecture features a custom second-layer sandbox with dynamic cordoning of tenants based on risk assessments. We’ve extended the V8 sandbox itself to leverage hardware features like MPK. We’ve teamed up with (and hired) leading researchers to develop novel defenses against Spectre. We also have systems that scan code for malicious patterns and automatically block them or apply additional layers of sandboxing. And much more.

When you use Dynamic Workers on Cloudflare, you get all of this automatically.

Helper libraries

We’ve built a number of libraries that you might find useful when working with Dynamic Workers:

Code Mode

@cloudflare/codemode simplifies running model-generated code against AI tools using Dynamic Workers. At its core is DynamicWorkerExecutor(), which constructs a purpose-built sandbox with code normalisation to handle common formatting errors, and direct access to a globalOutbound fetcher for controlling fetch() behaviour inside the sandbox — set it to null for full isolation, or pass a Fetcher binding to route, intercept or enrich outbound requests from the sandbox.

const executor = new DynamicWorkerExecutor({
  loader: env.LOADER,
  globalOutbound: null, // fully isolated 
});

const codemode = createCodeTool({
  tools: myTools,
  executor,
});

return generateText({
  model,
  messages,
  tools: { codemode },
});

The Code Mode SDK also provides two server-side utility functions. codeMcpServer({ server, executor }) wraps an existing MCP Server, replacing its tool surface with a single code() tool. openApiMcpServer({ spec, executor, request }) goes further: given an OpenAPI spec and an executor, it builds a complete MCP Server with search() and execute() tools as used by the Cloudflare MCP Server, and better suited to larger APIs.

In both cases, the code generated by the model runs inside Dynamic Workers, with calls to external services made over RPC bindings passed to the executor.

Learn more about the library and how to use it.

Bundling

Dynamic Workers expect pre-bundled modules. @cloudflare/worker-bundler handles that for you: give it source files and a package.json, and it resolves npm dependencies from the registry, bundles everything with esbuild, and returns the module map the Worker Loader expects.

import { createWorker } from "@cloudflare/worker-bundler";

const worker = env.LOADER.get("my-worker", async () => {
  const { mainModule, modules } = await createWorker({
    files: {
      "src/index.ts": `
        import { Hono } from 'hono';
        import { cors } from 'hono/cors';

        const app = new Hono();
        app.use('*', cors());
        app.get('/', (c) => c.text('Hello from Hono!'));
        app.get('/json', (c) => c.json({ message: 'It works!' }));

        export default app;
      `,
      "package.json": JSON.stringify({
        dependencies: { hono: "^4.0.0" }
      })
    }
  });

  return { mainModule, modules, compatibilityDate: "2026-01-01" };
});

await worker.getEntrypoint().fetch(request);

It also supports full-stack apps via createApp — bundle a server Worker, client-side JavaScript, and static assets together, with built-in asset serving that handles content types, ETags, and SPA routing.

Learn more about the library and how to use it.

File manipulation

@cloudflare/shell gives your agent a virtual filesystem inside a Dynamic Worker. Agent code calls typed methods on a state object — read, write, search, replace, diff, glob, JSON query/update, archive — with structured inputs and outputs instead of string parsing.

Storage is backed by a durable Workspace (SQLite + R2), so files persist across executions. Coarse operations like searchFiles, replaceInFiles, and planEdits minimize RPC round-trips — the agent issues one call instead of looping over individual files. Batch writes are transactional by default: if any write fails, earlier writes roll back automatically.

import { Workspace } from "@cloudflare/shell";
import { stateTools } from "@cloudflare/shell/workers";
import { DynamicWorkerExecutor, resolveProvider } from "@cloudflare/codemode";

const workspace = new Workspace({
  sql: this.ctx.storage.sql, // Works with any DO's SqlStorage, D1, or custom SQL backend
  r2: this.env.MY_BUCKET, // large files spill to R2 automatically
  name: () => this.name   // lazy — resolved when needed, not at construction
});

// Code runs in an isolated Worker sandbox with no network access
const executor = new DynamicWorkerExecutor({ loader: env.LOADER });

// The LLM writes this code; `state.*` calls dispatch back to the host via RPC
const result = await executor.execute(
  `async () => {
    // Search across all TypeScript files for a pattern
    const hits = await state.searchFiles("src/**/*.ts", "answer");
    // Plan multiple edits as a single transaction
    const plan = await state.planEdits([
      { kind: "replace", path: "/src/app.ts",
        search: "42", replacement: "43" },
      { kind: "writeJson", path: "/src/config.json",
        value: { version: 2 } }
    ]);
    // Apply atomically — rolls back on failure
    return await state.applyEditPlan(plan);
  }`,
  [resolveProvider(stateTools(workspace))]
);

The package also ships prebuilt TypeScript type declarations and a system prompt template, so you can drop the full state API into your LLM context in a handful of tokens.

Learn more about the library and how to use it.

How are people using it?

Code Mode

Developers want their agents to write and execute code against tool APIs, rather than making sequential tool calls one at a time. With Dynamic Workers, the LLM generates a single TypeScript function that chains multiple API calls together, runs it in a Dynamic Worker, and returns the final result back to the agent. As a result, only the output, and not every intermediate step, ends up in the context window. This cuts both latency and token usage, and produces better results, especially when the tool surface is large.

Our own Cloudflare MCP server is built exactly this way: it exposes the entire Cloudflare API through just two tools — search and execute — in under 1,000 tokens, because the agent writes code against a typed API instead of navigating hundreds of individual tool definitions.

Building custom automations 

Developers are using Dynamic Workers to let agents build custom automations on the fly. Zite, for example, is building an app platform where users interact through a chat interface — the LLM writes TypeScript behind the scenes to build CRUD apps, connect to services like Stripe, Airtable, and Google Calendar, and run backend logic, all without the user ever seeing a line of code. Every automation runs in its own Dynamic Worker, with access to only the specific services and libraries that the endpoint needs.

“To enable server-side code for Zite’s LLM-generated apps, we needed an execution layer that was instant, isolated, and secure. Cloudflare’s Dynamic Workers hit the mark on all three, and out-performed all of the other platforms we benchmarked for speed and library support. The NodeJS compatible runtime supported all of Zite’s workflows, allowing hundreds of third party integrations, without sacrificing on startup time. Zite now services millions of execution requests daily thanks to Dynamic Workers.”

Antony Toron, CTO and Co-Founder, Zite 

Running AI-generated applications

Developers are building platforms that generate full applications from AI — either for their customers or for internal teams building prototypes. With Dynamic Workers, each app can be spun up on demand, then put back into cold storage until it’s invoked again. Fast startup times make it easy to preview changes during active development. Platforms can also block or intercept any network requests the generated code makes, keeping AI-generated apps safe to run.

Pricing

Dynamically-loaded Workers are priced at $0.002 per unique Worker loaded per day (as of this post’s publication), in addition to the usual CPU time and invocation pricing of regular Workers.

For AI-generated “code mode” use cases, where every Worker is a unique one-off, this means the price is $0.002 per Worker loaded (plus CPU and invocations). This cost is typically negligible compared to the inference costs to generate the code.

During the beta period, the $0.002 charge is waived. As pricing is subject to change, please always check our Dynamic Workers pricing for the most current information. 

Get Started

If you’re on the Workers Paid plan, you can start using Dynamic Workers today. 

Dynamic Workers Starter

Use this “hello world” starter to get a Worker deployed that can load and execute Dynamic Workers. 

Dynamic Workers Playground

You can also deploy the Dynamic Workers Playground, where you’ll be able to write or import code, bundle it at runtime with @cloudflare/worker-bundler, execute it through a Dynamic Worker, see real-time responses and execution logs.


Dynamic Workers are fast, scalable, and lightweight. Find us on Discord if you have any questions. We’d love to see what you build!


Powering the agents: Workers AI now runs large models, starting with Kimi K2.5

Post Syndicated from Michelle Chen original https://blog.cloudflare.com/workers-ai-large-models/

We’re making Cloudflare the best place for building and deploying agents. But reliable agents aren’t built on prompts alone; they require a robust, coordinated infrastructure of underlying primitives.

At Cloudflare, we have been building these primitives for years: Durable Objects for state persistence, Workflows for long running tasks, and Dynamic Workers or Sandbox containers for secure execution. Powerful abstractions like the Agents SDK are designed to help you build agents on top of Cloudflare’s Developer Platform.

But these primitives only provided the execution environment. The agent still needed a model capable of powering it. 

Starting today, Workers AI is officially in the big models game. We now offer frontier open-source models on our AI inference platform. We’re starting by releasing Moonshot AI’s Kimi K2.5 model on Workers AI. With a full 256k context window and support for multi-turn tool calling, vision inputs, and structured outputs, the Kimi K2.5 model is excellent for all kinds of agentic tasks. By bringing a frontier-scale model directly into the Cloudflare Developer Platform, we’re making it possible to run the entire agent lifecycle on a single, unified platform.

The heart of an agent is the AI model that powers it, and that model needs to be smart, with high reasoning capabilities and a large context window. Workers AI now runs those models.

The price-performance sweet spot

We spent the last few weeks testing Kimi K2.5 as the engine for our internal development tools. Within our OpenCode environment, Cloudflare engineers use Kimi as a daily driver for agentic coding tasks. We have also integrated the model into our automated code review pipeline; you can see this in action via our public code review agent, Bonk, on Cloudflare GitHub repos. In production, the model has proven to be a fast, efficient alternative to larger proprietary models without sacrificing quality.

Serving Kimi K2.5 began as an experiment, but it quickly became critical after reviewing how the model performs and how cost-efficient it is. As an illustrative example: we have an agent that does security reviews of Cloudflare’s codebases. This agent processes over 7B tokens per day, and using Kimi, it has caught more than 15 confirmed issues in a single codebase. Doing some rough math, if we had run this agent on a mid-tier proprietary model, we would have spent $2.4M a year for this single use case, on a single codebase. Running this agent with Kimi K2.5 cost just a fraction of that: we cut costs by 77% simply by making the switch to Workers AI.

As AI adoption increases, we are seeing a fundamental shift not only in how engineering teams are operating, but how individuals are operating. It is becoming increasingly common for people to have a personal agent like OpenClaw running 24/7. The volume of inference is skyrocketing.

This new rise in personal and coding agents means that cost is no longer a secondary concern; it is the primary blocker to scaling. When every employee has multiple agents processing hundreds of thousands of tokens per hour, the math for proprietary models stops working. Enterprises will look to transition to open-source models that offer frontier-level reasoning without the proprietary price tag. Workers AI is here to facilitate this shift, providing everything from serverless endpoints for a personal agent to dedicated instances powering autonomous agents across an entire organization.

The large model inference stack

Workers AI has served models, including LLMs, since its launch two years ago, but we’ve historically prioritized smaller models. Part of the reason was that for some time, open-source LLMs fell far behind the models from frontier model labs. This changed with models like Kimi K2.5, but to serve this type of very large LLM, we had to make changes to our inference stack. We wanted to share with you some of what goes on behind the scenes to support a model like Kimi.

We’ve been working on custom kernels for Kimi K2.5 to optimize how we serve the model, which is built on top of our proprietary Infire inference engine. Custom kernels improve the model’s performance and GPU utilization, unlocking gains that would otherwise go unclaimed if you were just running the model out of the box. There are also multiple techniques and hardware configurations that can be leveraged to serve a large model. Developers typically use a combination of data, tensor, and expert parallelization techniques to optimize model performance. Strategies like disaggregated prefill are also important, in which you separate the prefill and generation stages onto different machines in order to get better throughput or higher GPU utilization. Implementing these techniques and incorporating them into the inference stack takes a lot of dedicated experience to get right. 

Workers AI has already done the experimentation with serving techniques to yield excellent throughput on Kimi K2.5. A lot of this does not come out of the box when you self-host an open-source model. The benefit of using a platform like Workers AI is that you don’t need to be a Machine Learning Engineer, a DevOps expert, or a Site Reliability Engineer to do the optimizations required to host it: we’ve already done the hard part, you just need to call an API.

Beyond the model — platform improvements for agentic workloads

In concert with this launch, we’ve also improved our platform and are releasing several new features to help you build better agents.

Prefix caching and surfacing cached tokens

When you work with agents, you are likely sending a large number of input tokens as part of the context: this could be detailed system prompts, tool definitions, MCP server tools, or entire codebases. Inputs can be as large as the model context window, so in theory, you could be sending requests with almost 256k input tokens. That’s a lot of tokens.

When an LLM processes a request, the request is broken down into two stages: the prefill stage processes input tokens and the output stage generates output tokens. These stages are usually sequential, where input tokens have to be fully processed before you can generate output tokens. This means that sometimes the GPU is not fully utilized while the model is doing prefill.

With multi-turn conversations, when you send a new prompt, the client sends all the previous prompts, tools, and context from the session to the model as well. The delta between consecutive requests is usually just a few new lines of input; all the other context has already gone through the prefill stage during a previous request. This is where prefix caching helps. Instead of doing prefill on the entire request, we can cache the input tensors from a previous request, and only do prefill on the new input tokens. This saves a lot of time and compute from the prefill stage, which means a faster Time to First Token (TTFT) and a higher Tokens Per Second (TPS) throughput as you’re not blocked on prefill.

Workers AI has always done prefix caching, but we are now surfacing cached tokens as a usage metric and offering a discount on cached tokens compared to input tokens. (Pricing can be found on the model page.) We also have new techniques for you to leverage in order to get a higher prefix cache hit rate, reducing your costs.

New session affinity header for higher cache hit rates

In order to route to the same model instance and take advantage of prefix caching, we use a new x-session-affinity header. When you send this header, you’ll improve your cache hit ratio, leading to more cached tokens and subsequently, faster TTFT, TPS, and lower inference costs.

You can pass the new header like below, with a unique string per session or per agent. Some clients like OpenCode implement this automatically out of the box. Our Agents SDK starter has already set up the wiring to do this for you, too.

curl -X POST \
"https://api.cloudflare.com/client/v4/accounts/{ACCOUNT_ID}/ai/run/@cf/moonshotai/kimi-k2.5" \
  -H "Authorization: Bearer {API_TOKEN}" \
  -H "Content-Type: application/json" \
  -H "x-session-affinity: ses_12345678" \
  -d '{
    "messages": [
      {
        "role": "system",
        "content": "You are a helpful assistant."
      },
      {
        "role": "user",
        "content": "What is prefix caching and why does it matter?"
      }
    ],
    "max_tokens": 2400,
    "stream": true
  }'

Redesigned async APIs

Serverless inference is really hard. With a pay-per-token business model, it’s cheaper on a single request basis because you don’t need to pay for entire GPUs to service your requests. But there’s a trade-off: you have to contend with other people’s traffic and capacity constraints, and there’s no strict guarantee that your request will be processed. This is not unique to Workers AI — it’s evidently the case across serverless model providers, given the frequent news reports of overloaded providers and service disruptions. While we always strive to serve your request and have built-in autoscaling and rebalancing, there are hard limitations (like hardware) that make this a challenge.
For volumes of requests that would exceed synchronous rate limits, you can submit batches of inferences to be completed asynchronously. We’re introducing a revamped Asynchronous API, which means that for asynchronous use cases, you won’t run into Out of Capacity errors and inference will execute durably at some point. Our async API looks more like flex processing than a batch API, where we process requests in the async queue as long as we have headroom in our model instances. With internal testing, our async requests usually execute within 5 minutes, but this will depend on what live traffic looks like. As we bring Kimi to the public, we will tune our scaling accordingly, but the async API is the best way to make sure you don’t run into capacity errors in durable workflows. This is perfect for use cases that are not real-time, such as code scanning agents or research agents.

Workers AI previously had an asynchronous API, but we’ve recently revamped the systems under the hood. We now rely on a pull-based system versus the historical push-based system, allowing us to pull in queued requests as soon as we have capacity. We’ve also added better controls to tune the throughput of async requests, monitoring GPU utilization in real-time and pulling in async requests when utilization is low, so that critical synchronous requests get priority while still processing asynchronous requests efficiently.

To use the asynchronous API, you would send your requests as seen below. We also have a way to set up event notifications so that you can know when the inference is complete instead of polling for the request. 

// (1.) Push a request in queue
// pass queueRequest: true
let res = await env.AI.run("@cf/moonshotai/kimi-k2.5", {
  "requests": [{
    "messages": [{
      "role": "user",
      "content": "Tell me a joke"
    }]
  }, {
    "messages": [{
      "role": "user",
      "content": "Explain the Pythagoras theorem"
    }]
  }, ...{<add more requests in a batch>} ];
}, {
  queueRequest: true,
});


// (2.) grab the request id
let request_id;
if(res && res.request_id){
  request_id = res.request_id;
}
// (3.) poll the status
let res = await env.AI.run("@cf/moonshotai/kimi-k2.5", {
  request_id: request_id
});

if(res && res.status === "queued" || res.status === "running") {
 // retry by polling again
 ...
}
else 
 return Response.json(res); // This will contain the final completed response 

Try it out today

Get started with Kimi K2.5 on Workers AI today. You can read our developer docs to find out model information and pricing, and how to take advantage of prompt caching via session affinity headers and asynchronous API. The Agents SDK starter also now uses Kimi K2.5 as its default model. You can also connect to Kimi K2.5 on Workers AI via Opencode. For a live demo, try it in our playground.

And if this set of problems around serverless inference, ML optimizations, and GPU infrastructure sound  interesting to you — we’re hiring!


How we rebuilt Next.js with AI in one week

Post Syndicated from Steve Faulkner original https://blog.cloudflare.com/vinext/

*This post was updated at 12:35 pm PT to fix a typo in the build time benchmarks.

Last week, one engineer and an AI model rebuilt the most popular front-end framework from scratch. The result, vinext (pronounced “vee-next”), is a drop-in replacement for Next.js, built on Vite, that deploys to Cloudflare Workers with a single command. In early benchmarks, it builds production apps up to 4x faster and produces client bundles up to 57% smaller. And we already have customers running it in production. 

The whole thing cost about $1,100 in tokens.

The Next.js deployment problem

Next.js is the most popular React framework. Millions of developers use it. It powers a huge chunk of the production web, and for good reason. The developer experience is top-notch.

But Next.js has a deployment problem when used in the broader serverless ecosystem. The tooling is entirely bespoke: Next.js has invested heavily in Turbopack but if you want to deploy it to Cloudflare, Netlify, or AWS Lambda, you have to take that build output and reshape it into something the target platform can actually run.

If you’re thinking: “Isn’t that what OpenNext does?”, you are correct. 

That is indeed the problem OpenNext was built to solve. And a lot of engineering effort has gone into OpenNext from multiple providers, including us at Cloudflare. It works, but quickly runs into limitations and becomes a game of whack-a-mole. 

Building on top of Next.js output as a foundation has proven to be a difficult and fragile approach. Because OpenNext has to reverse-engineer Next.js’s build output, this results in unpredictable changes between versions that take a lot of work to correct. 

Next.js has been working on a first-class adapters API, and we’ve been collaborating with them on it. It’s still an early effort but even with adapters, you’re still building on the bespoke Turbopack toolchain. And adapters only cover build and deploy. During development, next dev runs exclusively in Node.js with no way to plug in a different runtime. If your application uses platform-specific APIs like Durable Objects, KV, or AI bindings, you can’t test that code in dev without workarounds.

Introducing vinext


What if instead of adapting Next.js output, we reimplemented the Next.js API surface on Vite directly? Vite is the build tool used by most of the front-end ecosystem outside of Next.js, powering frameworks like Astro, SvelteKit, Nuxt, and Remix. A clean reimplementation, not merely a wrapper or adapter. We honestly didn’t think it would work. But it’s 2026, and the cost of building software has completely changed.

We got a lot further than we expected.

npm install vinext

Replace next with vinext in your scripts and everything else stays the same. Your existing app/, pages/, and next.config.js work as-is.

vinext dev          # Development server with HMR
vinext build        # Production build
vinext deploy       # Build and deploy to Cloudflare Workers

This is not a wrapper around Next.js and Turbopack output. It’s an alternative implementation of the API surface: routing, server rendering, React Server Components, server actions, caching, middleware. All of it built on top of Vite as a plugin. Most importantly Vite output runs on any platform thanks to the Vite Environment API.

The numbers

Early benchmarks are promising. We compared vinext against Next.js 16 using a shared 33-route App Router application.

Both frameworks are doing the same work: compiling, bundling, and preparing server-rendered routes. We disabled TypeScript type checking and ESLint in Next.js’s build (Vite doesn’t run these during builds), and used force-dynamic so Next.js doesn’t spend extra time pre-rendering static routes, which would unfairly slow down its numbers. The goal was to measure only bundler and compilation speed, nothing else. Benchmarks run on GitHub CI on every merge to main.

Production build time:

Framework Mean vs Next.js
Next.js 16.1.6 (Turbopack) 7.38s baseline
vinext (Vite 7 / Rollup) 4.64s 1.6x faster
vinext (Vite 8 / Rolldown) 1.67s 4.4x faster

Client bundle size (gzipped):

Framework Gzipped vs Next.js
Next.js 16.1.6 168.9 KB baseline
vinext (Rollup) 74.0 KB 56% smaller
vinext (Rolldown) 72.9 KB 57% smaller

These benchmarks measure compilation and bundling speed, not production serving performance. The test fixture is a single 33-route app, not a representative sample of all production applications. We expect these numbers to evolve as three projects continue to develop. The full methodology and historical results are public. Take them as directional, not definitive.

The direction is encouraging, though. Vite’s architecture, and especially Rolldown (the Rust-based bundler coming in Vite 8), has structural advantages for build performance that show up clearly here.

Deploying to Cloudflare Workers

vinext is built with Cloudflare Workers as the first deployment target. A single command takes you from source code to a running Worker:

vinext deploy

This handles everything: builds the application, auto-generates the Worker configuration, and deploys. Both the App Router and Pages Router work on Workers, with full client-side hydration, interactive components, client-side navigation, React state.

For production caching, vinext includes a Cloudflare KV cache handler that gives you ISR (Incremental Static Regeneration) out of the box:

import { KVCacheHandler } from "vinext/cloudflare";
import { setCacheHandler } from "next/cache";

setCacheHandler(new KVCacheHandler(env.MY_KV_NAMESPACE));

KV is a good default for most applications, but the caching layer is designed to be pluggable. That setCacheHandler call means you can swap in whatever backend makes sense. R2 might be a better fit for apps with large cached payloads or different access patterns. We’re also working on improvements to our Cache API that should provide a strong caching layer with less configuration. The goal is flexibility: pick the caching strategy that fits your app.

Live examples running right now:

We also have a live example of Cloudflare Agents running in a Next.js app, without the need for workarounds like getPlatformProxy, since the entire app now runs in workerd, during both dev and deploy phases. This means being able to use Durable Objects, AI bindings, and every other Cloudflare-specific service without compromise. Have a look here.

Frameworks are a team sport

The current deployment target is Cloudflare Workers, but that’s a small part of the picture. Something like 95% of vinext is pure Vite. The routing, the module shims, the SSR pipeline, the RSC integration: none of it is Cloudflare-specific.

Cloudflare is looking to work with other hosting providers about adopting this toolchain for their customers (the lift is minimal — we got a proof-of-concept working on Vercel in less than 30 minutes!). This is an open-source project, and for its long term success, we believe it’s important we work with partners across the ecosystem to ensure ongoing investment. PRs from other platforms are welcome. If you’re interested in adding a deployment target, open an issue or reach out.

Status: Experimental

We want to be clear: vinext is experimental. It’s not even one week old, and it has not yet been battle-tested with any meaningful traffic at scale. If you’re evaluating it for a production application, proceed with appropriate caution.

That said, the test suite is extensive: over 1,700 Vitest tests and 380 Playwright E2E tests, including tests ported directly from the Next.js test suite and OpenNext’s Cloudflare conformance suite. We’ve verified it against the Next.js App Router Playground. Coverage sits at 94% of the Next.js 16 API surface.

Early results from real-world customers are encouraging. We’ve been working with National Design Studio, a team that’s aiming to modernize every government interface, on one of their beta sites, CIO.gov. They’re already running vinext in production, with meaningful improvements in build times and bundle sizes.

The README is honest about what’s not supported and won’t be, and about known limitations. We want to be upfront rather than overpromise.

What about pre-rendering?

vinext already supports Incremental Static Regeneration (ISR) out of the box. After the first request to any page, it’s cached and revalidated in the background, just like Next.js. That part works today.

vinext does not yet support static pre-rendering at build time. In Next.js, pages without dynamic data get rendered during next build and served as static HTML. If you have dynamic routes, you use generateStaticParams() to enumerate which pages to build ahead of time. vinext doesn’t do that… yet.

This was an intentional design decision for launch. It’s on the roadmap, but if your site is 100% prebuilt HTML with static content, you probably won’t see much benefit from vinext today. That said, if one engineer can spend $1,100 in tokens and rebuild Next.js, you can probably spend $10 and migrate to a Vite-based framework designed specifically for static content, like Astro (which also deploys to Cloudflare Workers).

For sites that aren’t purely static, though, we think we can do something better than pre-rendering everything at build time.

Introducing Traffic-aware Pre-Rendering

Next.js pre-renders every page listed in generateStaticParams() during the build. A site with 10,000 product pages means 10,000 renders at build time, even though 99% of those pages may never receive a request. Builds scale linearly with page count. This is why large Next.js sites end up with 30-minute builds.

So we built Traffic-aware Pre-Rendering (TPR). It’s experimental today, and we plan to make it the default once we have more real-world testing behind it.

The idea is simple. Cloudflare is already the reverse proxy for your site. We have your traffic data. We know which pages actually get visited. So instead of pre-rendering everything or pre-rendering nothing, vinext queries Cloudflare’s zone analytics at deploy time and pre-renders only the pages that matter.

vinext deploy --experimental-tpr

  Building...
  Build complete (4.2s)

  TPR (experimental): Analyzing traffic for my-store.com (last 24h)
  TPR: 12,847 unique paths — 184 pages cover 90% of traffic
  TPR: Pre-rendering 184 pages...
  TPR: Pre-rendered 184 pages in 8.3s → KV cache

  Deploying to Cloudflare Workers...

For a site with 100,000 product pages, the power law means 90% of traffic usually goes to 50 to 200 pages. Those get pre-rendered in seconds. Everything else falls back to on-demand SSR and gets cached via ISR after the first request. Every new deploy refreshes the set based on current traffic patterns. Pages that go viral get picked up automatically. All of this works without generateStaticParams() and without coupling your build to your production database.

Taking on the Next.js challenge, but this time with AI

A project like this would normally take a team of engineers months, if not years. Several teams at various companies have attempted it, and the scope is just enormous. We tried once at Cloudflare! Two routers, 33+ module shims, server rendering pipelines, RSC streaming, file-system routing, middleware, caching, static export. There’s a reason nobody has pulled it off.

This time we did it in under a week. One engineer (technically engineering manager) directing AI.

The first commit landed on February 13. By the end of that same evening, both the Pages Router and App Router had basic SSR working, along with middleware, server actions, and streaming. By the next afternoon, App Router Playground was rendering 10 of 11 routes. By day three, vinext deploy was shipping apps to Cloudflare Workers with full client hydration. The rest of the week was hardening: fixing edge cases, expanding the test suite, bringing API coverage to 94%.

What changed from those earlier attempts? AI got better. Way better.

Why this problem is made for AI

Not every project would go this way. This one did because a few things happened to line up at the right time.

Next.js is well-specified. It has extensive documentation, a massive user base, and years of Stack Overflow answers and tutorials. The API surface is all over the training data. When you ask Claude to implement getServerSideProps or explain how useRouter works, it doesn’t hallucinate. It knows how Next works.

Next.js has an elaborate test suite. The Next.js repo contains thousands of E2E tests covering every feature and edge case. We ported tests directly from their suite (you can see the attribution in the code). This gave us a specification we could verify against mechanically.

Vite is an excellent foundation. Vite handles the hard parts of front-end tooling: fast HMR, native ESM, a clean plugin API, production bundling. We didn’t have to build a bundler. We just had to teach it to speak Next.js. @vitejs/plugin-rsc is still early, but it gave us React Server Components support without having to build an RSC implementation from scratch.

The models caught up. We don’t think this would have been possible even a few months ago. Earlier models couldn’t sustain coherence across a codebase this size. New models can hold the full architecture in context, reason about how modules interact, and produce correct code often enough to keep momentum going. At times, I saw it go into Next, Vite, and React internals to figure out a bug. The state-of-the-art models are impressive, and they seem to keep getting better.

All of those things had to be true at the same time. Well-documented target API, comprehensive test suite, solid build tool underneath, and a model that could actually handle the complexity. Take any one of them away and this doesn’t work nearly as well.

How we actually built it

Almost every line of code in vinext was written by AI. But here’s the thing that matters more: every line passes the same quality gates you’d expect from human-written code. The project has 1,700+ Vitest tests, 380 Playwright E2E tests, full TypeScript type checking via tsgo, and linting via oxlint. Continuous integration runs all of it on every pull request. Establishing a set of good guardrails is critical to making AI productive in a codebase.

The process started with a plan. I spent a couple of hours going back and forth with Claude in OpenCode to define the architecture: what to build, in what order, which abstractions to use. That plan became the north star. From there, the workflow was straightforward:

  1. Define a task (“implement the next/navigation shim with usePathname, useSearchParams, useRouter“).

  2. Let the AI write the implementation and tests.

  3. Run the test suite.

  4. If tests pass, merge. If not, give the AI the error output and let it iterate.

  5. Repeat.

We wired up AI agents for code review too. When a PR was opened, an agent reviewed it. When review comments came back, another agent addressed them. The feedback loop was mostly automated.

It didn’t work perfectly every time. There were PRs that were just wrong. The AI would confidently implement something that seemed right but didn’t match actual Next.js behavior. I had to course-correct regularly. Architecture decisions, prioritization, knowing when the AI was headed down a dead end: that was all me. When you give AI good direction, good context, and good guardrails, it can be very productive. But the human still has to steer.

For browser-level testing, I used agent-browser to verify actual rendered output, client-side navigation, and hydration behavior. Unit tests miss a lot of subtle browser issues. This caught them.

Over the course of the project, we ran over 800 sessions in OpenCode. Total cost: roughly $1,100 in Claude API tokens.

What this means for software

Why do we have so many layers in the stack? This project forced me to think deeply about this question. And to consider how AI impacts the answer.

Most abstractions in software exist because humans need help. We couldn’t hold the whole system in our heads, so we built layers to manage the complexity for us. Each layer made the next person’s job easier. That’s how you end up with frameworks on top of frameworks, wrapper libraries, thousands of lines of glue code.

AI doesn’t have the same limitation. It can hold the whole system in context and just write the code. It doesn’t need an intermediate framework to stay organized. It just needs a spec and a foundation to build on.

It’s not clear yet which abstractions are truly foundational and which ones were just crutches for human cognition. That line is going to shift a lot over the next few years. But vinext is a data point. We took an API contract, a build tool, and an AI model, and the AI wrote everything in between. No intermediate framework needed. We think this pattern will repeat across a lot of software. The layers we’ve built up over the years aren’t all going to make it.

Acknowledgments

Thanks to the Vite team. Vite is the foundation this whole thing stands on. @vitejs/plugin-rsc is still early days, but it gave me RSC support without having to build that from scratch, which would have been a dealbreaker. The Vite maintainers were responsive and helpful as I pushed the plugin into territory it hadn’t been tested in before.

We also want to acknowledge the Next.js team. They’ve spent years building a framework that raised the bar for what React development could look like. The fact that their API surface is so well-documented and their test suite so comprehensive is a big part of what made this project possible. vinext wouldn’t exist without the standard they set.

Try it

vinext includes an Agent Skill that handles migration for you. It works with Claude Code, OpenCode, Cursor, Codex, and dozens of other AI coding tools. Install it, open your Next.js project, and tell the AI to migrate:

npx skills add cloudflare/vinext

Then open your Next.js project in any supported tool and say:

migrate this project to vinext

The skill handles compatibility checking, dependency installation, config generation, and dev server startup. It knows what vinext supports and will flag anything that needs manual attention.

Or if you prefer doing it by hand:

npx vinext init    # Migrate an existing Next.js project
npx vinext dev     # Start the dev server
npx vinext deploy  # Ship to Cloudflare Workers

The source is at github.com/cloudflare/vinext. Issues, PRs, and feedback are welcome.

Code Mode: give agents an entire API in 1,000 tokens

Post Syndicated from Matt Carey original https://blog.cloudflare.com/code-mode-mcp/

Model Context Protocol (MCP) has become the standard way for AI agents to use external tools. But there is a tension at its core: agents need many tools to do useful work, yet every tool added fills the model’s context window, leaving less room for the actual task.

Code Mode is a technique we first introduced for reducing context window usage during agent tool use. Instead of describing every operation as a separate tool, let the model write code against a typed SDK and execute the code safely in a Dynamic Worker Loader. The code acts as a compact plan. The model can explore tool operations, compose multiple calls, and return just the data it needs. Anthropic independently explored the same pattern in their Code Execution with MCP post.

Today we are introducing a new MCP server for the entire Cloudflare API — from DNS and Zero Trust to Workers and R2 — that uses Code Mode. With just two tools, search() and execute(), the server is able to provide access to the entire Cloudflare API over MCP, while consuming only around 1,000 tokens. The footprint stays fixed, no matter how many API endpoints exist.

For a large API like the Cloudflare API, Code Mode reduces the number of input tokens used by 99.9%. An equivalent MCP server without Code Mode would consume 1.17 million tokens — more than the entire context window of the most advanced foundation models.


Code mode savings vs native MCP, measured with tiktoken

You can start using this new Cloudflare MCP server today. And we are also open-sourcing a new Code Mode SDK in the Cloudflare Agents SDK, so you can use the same approach in your own MCP servers and AI Agents.

Server‑side Code Mode


This new MCP server applies Code Mode server-side. Instead of thousands of tools, the server exports just two: search() and execute(). Both are powered by Code Mode. Here is the full tool surface area that gets loaded into the model context:

[
  {
    "name": "search",
    "description": "Search the Cloudflare OpenAPI spec. All $refs are pre-resolved inline.",
    "inputSchema": {
      "type": "object",
      "properties": {
        "code": {
          "type": "string",
          "description": "JavaScript async arrow function to search the OpenAPI spec"
        }
      },
      "required": ["code"]
    }
  },
  {
    "name": "execute",
    "description": "Execute JavaScript code against the Cloudflare API.",
    "inputSchema": {
      "type": "object",
      "properties": {
        "code": {
          "type": "string",
          "description": "JavaScript async arrow function to execute"
        }
      },
      "required": ["code"]
    }
  }
]

To discover what it can do, the agent calls search(). It writes JavaScript against a typed representation of the OpenAPI spec. The agent can filter endpoints by product, path, tags, or any other metadata and narrow thousands of endpoints to the handful it needs. The full OpenAPI spec never enters the model context. The agent only interacts with it through code.

When the agent is ready to act, it calls execute(). The agent writes code that can make Cloudflare API requests, handle pagination, check responses, and chain operations together in a single execution. 

Both tools run the generated code inside a Dynamic Worker isolate — a lightweight V8 sandbox with no file system, no environment variables to leak through prompt injection and external fetches disabled by default. Outbound requests can be explicitly controlled with outbound fetch handlers when needed.

Example: Protecting an origin from DDoS attacks

Suppose a user tells their agent: “protect my origin from DDoS attacks.” The agent’s first step is to consult documentation. It might call the Cloudflare Docs MCP Server, use a Cloudflare Skill, or search the web directly. From the docs it learns: put Cloudflare WAF and DDoS protection rules in front of the origin.

Step 1: Search for the right endpoints
The search tool gives the model a spec object: the full Cloudflare OpenAPI spec with all $refs pre-resolved. The model writes JavaScript against it. Here the agent looks for WAF and ruleset endpoints on a zone:

async () => {
  const results = [];
  for (const [path, methods] of Object.entries(spec.paths)) {
    if (path.includes('/zones/') &&
        (path.includes('firewall/waf') || path.includes('rulesets'))) {
      for (const [method, op] of Object.entries(methods)) {
        results.push({ method: method.toUpperCase(), path, summary: op.summary });
      }
    }
  }
  return results;
}

The server runs this code in a Workers isolate and returns:

[
  { "method": "GET",    "path": "/zones/{zone_id}/firewall/waf/packages",              "summary": "List WAF packages" },
  { "method": "PATCH",  "path": "/zones/{zone_id}/firewall/waf/packages/{package_id}", "summary": "Update a WAF package" },
  { "method": "GET",    "path": "/zones/{zone_id}/firewall/waf/packages/{package_id}/rules", "summary": "List WAF rules" },
  { "method": "PATCH",  "path": "/zones/{zone_id}/firewall/waf/packages/{package_id}/rules/{rule_id}", "summary": "Update a WAF rule" },
  { "method": "GET",    "path": "/zones/{zone_id}/rulesets",                           "summary": "List zone rulesets" },
  { "method": "POST",   "path": "/zones/{zone_id}/rulesets",                           "summary": "Create a zone ruleset" },
  { "method": "GET",    "path": "/zones/{zone_id}/rulesets/phases/{ruleset_phase}/entrypoint", "summary": "Get a zone entry point ruleset" },
  { "method": "PUT",    "path": "/zones/{zone_id}/rulesets/phases/{ruleset_phase}/entrypoint", "summary": "Update a zone entry point ruleset" },
  { "method": "POST",   "path": "/zones/{zone_id}/rulesets/{ruleset_id}/rules",        "summary": "Create a zone ruleset rule" },
  { "method": "PATCH",  "path": "/zones/{zone_id}/rulesets/{ruleset_id}/rules/{rule_id}", "summary": "Update a zone ruleset rule" }
]

The full Cloudflare API spec has over 2,500 endpoints. The model narrowed that to the WAF and ruleset endpoints it needs, without any of the spec entering the context window. 

The model can also drill into a specific endpoint’s schema before calling it. Here it inspects what phases are available on zone rulesets:

async () => {
  const op = spec.paths['/zones/{zone_id}/rulesets']?.get;
  const items = op?.responses?.['200']?.content?.['application/json']?.schema;
  // Walk the schema to find the phase enum
  const props = items?.allOf?.[1]?.properties?.result?.items?.allOf?.[1]?.properties;
  return { phases: props?.phase?.enum };
}

{
  "phases": [
    "ddos_l4", "ddos_l7",
    "http_request_firewall_custom", "http_request_firewall_managed",
    "http_response_firewall_managed", "http_ratelimit",
    "http_request_redirect", "http_request_transform",
    "magic_transit", "magic_transit_managed"
  ]
}

The agent now knows the exact phases it needs: ddos_l7 for DDoS protection and http_request_firewall_managed for WAF.

Step 2: Act on the API
The agent switches to using execute. The sandbox gets a cloudflare.request() client that can make authenticated calls to the Cloudflare API. First the agent checks what rulesets already exist on the zone:

async () => {
  const response = await cloudflare.request({
    method: "GET",
    path: `/zones/${zoneId}/rulesets`
  });
  return response.result.map(rs => ({
    name: rs.name, phase: rs.phase, kind: rs.kind
  }));
}

[
  { "name": "DDoS L7",          "phase": "ddos_l7",                        "kind": "managed" },
  { "name": "Cloudflare Managed","phase": "http_request_firewall_managed", "kind": "managed" },
  { "name": "Custom rules",     "phase": "http_request_firewall_custom",   "kind": "zone" }
]

The agent sees that managed DDoS and WAF rulesets already exist. It can now chain calls to inspect their rules and update sensitivity levels in a single execution:

async () => {
  // Get the current DDoS L7 entrypoint ruleset
  const ddos = await cloudflare.request({
    method: "GET",
    path: `/zones/${zoneId}/rulesets/phases/ddos_l7/entrypoint`
  });

  // Get the WAF managed ruleset
  const waf = await cloudflare.request({
    method: "GET",
    path: `/zones/${zoneId}/rulesets/phases/http_request_firewall_managed/entrypoint`
  });
}

This entire operation, from searching the spec and inspecting a schema to listing rulesets and fetching DDoS and WAF configurations, took four tool calls.

The Cloudflare MCP server

We started with MCP servers for individual products. Want an agent that manages DNS? Add the DNS MCP server. Want Workers logs? Add the Workers Observability MCP server. Each server exported a fixed set of tools that mapped to API operations. This worked when the tool set was small, but the Cloudflare API has over 2,500 endpoints. No collection of hand-maintained servers could keep up.

The Cloudflare MCP server simplifies this. Two tools, roughly 1,000 tokens, and coverage of every endpoint in the API. When we add new products, the same search() and execute() code paths discover and call them — no new tool definitions, no new MCP servers. It even has support for the GraphQL Analytics API.

Our MCP server is built on the latest MCP specifications. It is OAuth 2.1 compliant, using Workers OAuth Provider to downscope the token to selected permissions approved by the user when connecting. The agent  only gets the capabilities the user explicitly granted. 

For developers, this means you can use a simple agent loop and still give your agent access to the full Cloudflare API with built-in progressive capability discovery.


Comparing approaches to context reduction

Several approaches have emerged to reduce how many tokens MCP tools consume:

Client-side Code Mode was our first experiment. The model writes TypeScript against typed SDKs and runs it in a Dynamic Worker Loader on the client. The tradeoff is that it requires the agent to ship with secure sandbox access. Code Mode is implemented in Goose and Anthropics Claude SDK as Programmatic Tool Calling.

Command-line interfaces are another path. CLIs are self-documenting and reveal capabilities as the agent explores. Tools like OpenClaw and Moltworker convert MCP servers into CLIs using MCPorter to give agents progressive disclosure. The limitation is obvious: the agent needs a shell, which not every environment provides and which introduces a much broader attack surface than a sandboxed isolate.

Dynamic tool search, as used by Anthropic in Claude Code, surfaces a smaller set of tools hopefully relevant to the current task. It shrinks context use but now requires a search function that must be maintained and evaluated, and each matched tool still uses tokens.


Each approach solves a real problem. But for MCP servers specifically, server-side Code Mode combines their strengths: fixed token cost regardless of API size, no modifications needed on the agent side, progressive discovery built in, and safe execution inside a sandboxed isolate. The agent just calls two tools with code. Everything else happens on the server.

Get started today

The Cloudflare MCP server is available now. Point your MCP client at the server URL and you’ll be redirected to Cloudflare to authorize and select the permissions to grant to your agent. Add this config to your MCP client: 

{
  "mcpServers": {
    "cloudflare-api": {
      "url": "https://mcp.cloudflare.com/mcp"
    }
  }
}

For CI/CD, automation, or if you prefer managing tokens yourself, create a Cloudflare API token with the permissions you need. Both user tokens and account tokens are supported and can be passed as bearer tokens in the Authorization header.

More information on different MCP setup configurations can be found at the Cloudflare MCP repository.

Looking forward

Code Mode solves context costs for a single API. But agents rarely talk to one service. A developer’s agent might need the Cloudflare API alongside GitHub, a database, and an internal docs server. Each additional MCP server brings the same context window pressure we started with.

Cloudflare MCP Server Portals let you compose multiple MCP servers behind a single gateway with unified auth and access control. We are building a first-class Code Mode integration for all your MCP servers, and exposing them to agents with built-in progressive discovery and the same fixed-token footprint, regardless of how many services sit behind the gateway.