Post Syndicated from Curious Droid original https://www.youtube.com/watch?v=tSZjjUO7Jn0
ICE & Expedited Removal #lastweektonight
Post Syndicated from LastWeekTonight original https://www.youtube.com/shorts/o6g62JCgWxc
Comic for 2025.08.17 – Comedian In The 1600s
Post Syndicated from Explosm.net original https://explosm.net/comics/comedian-in-the-1600s
New Cyanide and Happiness Comic
2025-08-17 Adventures in Linux bonding
Post Syndicated from Vasil Kolev original https://vasil.ludost.net/blog/?p=3509
All this comes from our work on getting a stable and redundant link for servers without resorting to things like routing protocols, and is the product of some years of “research” (hitting the next problem and solving it).
The Linux kernel has a (deceptively simple) mechanism for “bonding” two interfaces as one, to use for load-balancing and fail-over. It is really well documented in https://www.kernel.org/doc/Documentation/networking/bonding.txt and if some of my explanations are lacking, that’s the proper document to look into.
There are all kinds of modes, but there are two that make sense in Ethernet networks – active-backup and 802.1ad. 802.1ad requires support from the switch side, and for proper redundancy when you’re connecting to two switches to have them stacked or clustered. Stacked switches crash together, clustered also, but a bit less. So, for proper redundancy you’d like to have the two switches you connect to as independent as possible, which rules out 802.1ad.
(802.1ad is also known as LACP, link aggregation control protocol. When connecting to two different switches, it’s known as MLAG, multi-chassis link aggregation.)
For the sake of illustration, let’s say we have a network with two switches (SW1 and SW2) and two hosts, A and B. A is connected to SW1 and SW2, so is B.
By default the active-backup bond just monitors the state of the link (“miimon”). This should work in a better world, where switches are supposed to die completely when they can’t forward packets, but that’s not the case in the real world. Even without the “fun” failure modes where a switch stops forwarding without killing the links, there’s also the option that someone mis-configures a VLAN and blackholes the traffic you care about. As miimon can’t detect any such issues and fail-over to the other interfaces, it’s not very useful in Ethernet networks.
There is another option, something called “ARP monitor” – the bond sends ARP requests to a set of pre-configured targets and listens for the replies, if the replies stop, the interface is deemed dead and failed-over. This is a step in the right direction.
To have this properly configured, you need to have more than one target (so the death of that one target does not make the node think it has no connectivity), and to configure it for any node in the targets to be reachable to make the link active (the arp_all_targets option). All these are somewhat obvious and easy to set up, together with the preferred arp_interval to know how often to send packets.
And all this would’ve been fine if not for the weird default behavior of the Linux bonding to take any received ARP traffic as an indication that the link is OK. So if you get disconnected from the targets, but there are some other hosts in the partition created on that “side” of the network, you’ll never switch to the other interface, never mind that you can’t reach the targets via the current active interface.
The next option is called “arp_validate”. It tells the bond to actually look in the received ARP traffic if it’s from the targets (well, almost, but we’ll get to that). It can be told to look to “validate” no interface, the active one, or both. I have no idea why the validation is not “on” by default, and I haven’t dug in the history enough to check, but I’m guessing it’s something related to the weak host model and the issues I’ve had with ARP.
“arp_validate=active” takes care of checking what’s received on the currently active interface, so it should resolve most issues. However, it doesn’t help when the backup interface is not correctly connected and receives some ARP traffic, and it’s not possible to check /proc/net/bonding/bondX and know if it’s safe to switch the active interface for some reason (so you switch, and hopefully bounce back pretty quickly). To allow for monitoring the state of the backup interface, you should use “arp_validate=all”.
Which would be great if that worked. This part took me some reading of the sources to get right, see this part of bond_arp_rcv() in drivers/net/bonding/bond_main.c, especially the three calls to bond_validate_arp() on lines 3284, 3288 and 3290. Is there something weird there?
That’s correct, in the check on line 3288 the “tip” and “sip” arguments (source and destination) are swapped. A closer reading of the documentation and the source shows that if you validate the traffic to the backup interface, the ONLY traffic that will make this interface “up” is our own broadcast traffic send to the targets, not for example broadcasts received from the targets themselves (which I expected to be the case). I’m thinking about submitting a patch to the documentation in that regard.
So, in general this should work, but we had a lot of cases where the backup interface refused to hear the broadcasts sent via the active interface. After some time we were able to trace these cases to two specific NIC drivers – i40e and ice, both Intel NICs.
Small bit of theory before explaining what the issue was – the Linux bond sets the same MAC address on all Ethernet interfaces in the same bond.
And, there’s this small option called source pruning, which roughly translates to “drop all received packets that have my MAC address as source”. Which might make sense in some situations, but definitely not in a bond with “arp_validate=all”. So, for i40e this is just an ethtool option, but for ice NICs this looks to be hardcoded, and I’ve opened an issue for this to be configurable, so hopefully in some years it’ll get fixed.
postscript 1:
bpftrace is a wonderful tool that helped a lot to attach to the bond_arp_rcv() and other functions and see what’s going on. For any issue which strace can’t see (like “something returns EINVAL and you have no idea why), this looks to be the next step.
postscript 2:
I noted that two bonding mechanisms make sense in Ethernet network. There are some more modes, which are either “broadcast” (send all packets via all links) or “balance the traffic based on a function”. Both these types of modes will weird out the switches, because they’ll see traffic from the same MAC address coming from two different places and would constantly be updating their tables where these MACs are, with very fun consequences.
These modes made a lot more sense for serial links back in the days, adding two SLIP or PPP links to a bond with the default mode (balance with round-robin) was the cheapest way to get twice the bandwidth without any extra complexity.
The most resilient (but hardest to implement and more complex) solution for anything like this would be full-mesh BFD and BGP, which would make sure you only use paths that you can communicate on (doesn’t help with MTU blackholes, but pretty much nothing does). I’ve never seen it done, though 🙂
The Ghost Blimp
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/shorts/CHriZYsEQk0
Hook
Post Syndicated from Oglaf! -- Comics. Often dirty. original https://www.oglaf.com/hook/

Phison Pascari D205V 122.88TB NVMe SSD at FMS 2025
Post Syndicated from Cliff Robinson original https://www.servethehome.com/phison-pascari-d205v-122-88tb-nvme-ssd-at-fms-2025/
We saw the Phison Pascari D205V 122.88TB NVMe SSDs at FMS 2025 in both U.2 and E3.L PCIe Gen5 form factors
The post Phison Pascari D205V 122.88TB NVMe SSD at FMS 2025 appeared first on ServeTheHome.
The Washington Monument: Honoring The Father of a Nation
Post Syndicated from Geographics original https://www.youtube.com/watch?v=85bZWxTmdy0
Is VHS back? No, but I bought a ‘new’ VHS release.
Post Syndicated from Techmoan original https://www.youtube.com/watch?v=PC94KQtNPWs
ASRock Rack AMPONED8-2T BCM AmpereOne Motherboard at FMS 2025
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/asrock-rack-amponed8-2t-bcm-ampereone-motherboard-at-fms-2025/
The ASRock Rack AMPONED8-2T/BCM is a standard format motherboard that uses the Arm-based Ampere AmpereOne processors along with lots of I/O
The post ASRock Rack AMPONED8-2T BCM AmpereOne Motherboard at FMS 2025 appeared first on ServeTheHome.
The Cloud Cover Changed
Post Syndicated from The History Guy: History Deserves to Be Remembered original https://www.youtube.com/shorts/tBrd62Rl5eo
Comic for 2025.08.16 – Nobody Listens
Post Syndicated from Explosm.net original https://explosm.net/comics/nobody-listens
New Cyanide and Happiness Comic
Friday Squid Blogging: Squid-Shaped UFO Spotted Over Texas
Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2025/08/friday-squid-blogging-squid-shaped-ufo-spotted-over-texas.html
Here’s the story. The commenters on X (formerly Twitter) are unimpressed.
As usual, you can also use this squid post to talk about the security stories in the news that I haven’t covered.
Transform your data to Amazon S3 Tables with Amazon Athena
Post Syndicated from Pathik Shah original https://aws.amazon.com/blogs/big-data/transform-your-data-to-amazon-s3-tables-with-amazon-athena/
Organizations today manage vast amounts of data, with much of it stored based on initial use cases and business needs. As requirements for this data evolve—whether for real-time reporting, advanced machine learning (ML), or cross-team data sharing—the original storage formats and structures often become a bottleneck. When this happens, data teams frequently find that datasets that worked well for their original purpose now require complex transformations; custom extract, transform, and load (ETL) pipelines; and extensive redesign to unblock new analytical workflows. This creates a significant barrier between valuable data and actionable insights.
Amazon Athena offers a solution through its serverless, SQL-based approach to data transformation. With the CREATE TABLE AS SELECT (CTAS) functionality in Athena, you can transform existing data and create new tables in the process, using standard SQL statements to help reduce the need for custom ETL pipeline development.
This CTAS experience now supports Amazon S3 Tables, which provide built-in optimization, Apache Iceberg support, automatic table maintenance, and ACID transaction capabilities. This combination can help organizations modernize their data infrastructure, achieve improved performance, and reduce operational overhead.
You can use this approach to transform data from commonly used tabular formats, including CSV, TSV, JSON, Avro, Parquet, and ORC. The resulting tables are immediately accessible for querying across Athena, Amazon Redshift, Amazon EMR, and supported third-party applications, including Apache Spark, Trino, DuckDB, and PyIceberg.
This post demonstrates how Athena CTAS simplifies the data transformation process through a practical example: migrating an existing Parquet dataset into S3 Tables.
Solution overview
Consider a global apparel ecommerce retailer processing thousands of daily customer reviews across marketplaces. Their dataset, currently stored in Parquet format in Amazon Simple Storage Service (Amazon S3), requires updates whenever customers modify ratings and review content. The business needs a solution that supports ACID transactions—the ability to atomically insert, update, and delete records while maintaining data consistency—because review data changes frequently as customers edit their feedback.
Additionally, the data team faces operational challenges: manual table maintenance tasks like compaction and metadata management, no built-in support for time travel queries to analyze historical changes, and the need for custom processes to handle concurrent data modifications safely.
These requirements point to a need for an analytics-friendly solution that can handle transactional workloads while providing automated table maintenance, reducing the operational overhead that currently burdens their analysts and engineers.
S3 Tables and Athena provide an ideal solution for these requirements. S3 Tables provide storage optimized for analytics workloads, offering Iceberg support with automatic table maintenance and continuous optimization. Athena is a serverless, interactive query service you can use to analyze data using standard SQL without managing infrastructure. When combined, S3 Tables handle the storage optimization and maintenance automatically, and Athena provides the SQL interface for data transformation and querying. This can help reduce the operational overhead of manual table maintenance while providing efficient data management and optimal performance across supported data processing and query engines.
In the following sections, we show how to use the CTAS functionality in Athena to transform the Parquet-formatted review data into S3 Tables with a single SQL statement. We then demonstrate how to manage dynamic data using INSERT, UPDATE, and DELETE operations, showcasing the ACID transaction capabilities and metadata query features in S3 Tables.
Prerequisites
In this walkthrough, we will be working with synthetic customer review data that we’ve made publicly available at s3://aws-bigdata-blog/generated_synthetic_reviews/data/. To follow along, you must have the following prerequisites:
- AWS account setup:
- Access to AWS services: Athena, S3 Tables, Amazon S3, AWS Identity and Access Management (IAM), AWS Lake Formation, and the AWS Glue Data Catalog
- Access to the AWS Management Console
- An existing Athena workgroup configured with SQL engine
- An IAM user or role with the following permissions:
AmazonAthenaFullAccessmanaged policy- S3 Tables permissions for creating and managing table buckets
- S3 Tables permissions for creating and managing tables within buckets
- Read access to the public dataset location:
s3://aws-bigdata-blog/generated_synthetic_reviews/data/
You will create an S3 table bucket named athena-ctas-s3table-demo as part of this walkthrough. Make sure this name is available in your chosen AWS Region.
Set up a database and tables in Athena
Let’s start by creating a database and source table to hold our Parquet data. This table will serve as the data source for our CTAS operation.
Navigate to the Athena query editor to run the following queries:
Because the data is partitioned by product category, you must add the partition information to the table metadata using MSCK REPAIR TABLE:
The preview query should return sample review data, confirming the table is ready for transformation:
Create a table bucket
Table buckets are designed to store tabular data and metadata as objects for analytics workloads. Follow these steps to create a table bucket:
- Sign in to the console in your preferred Region and open the Amazon S3 console.
- In the navigation pane, choose Table buckets.
- Choose Create table bucket.
- For Table bucket name, enter
athena-ctas-s3table-demo. - Select Enable integration for Integration with AWS analytics services if not already enabled.
- Leave the encryption option to default.
- Choose Create table bucket.
You can now see athena-ctas-s3table-demo listed under Table buckets.
Create a namespace
Namespaces provide logical organization for tables within your S3 table bucket, facilitating scalable table management. In this step, we create a reviews_namespace to organize our customer review tables. Follow these steps to create the table namespace:
- In the navigation pane under Table buckets, choose your newly created bucket
athena-ctas-s3table-demo. - On the bucket details page, choose Create table with Athena.
- Choose Create a namespace for Namespace configuration.
- Enter
reviews_namespacefor Namespace name. - Choose Create namespace.
- Choose Create table with Athena to navigate to the Athena query editor.
You should now see your S3 Tables configuration automatically selected under Data, as shown in the following screenshot.
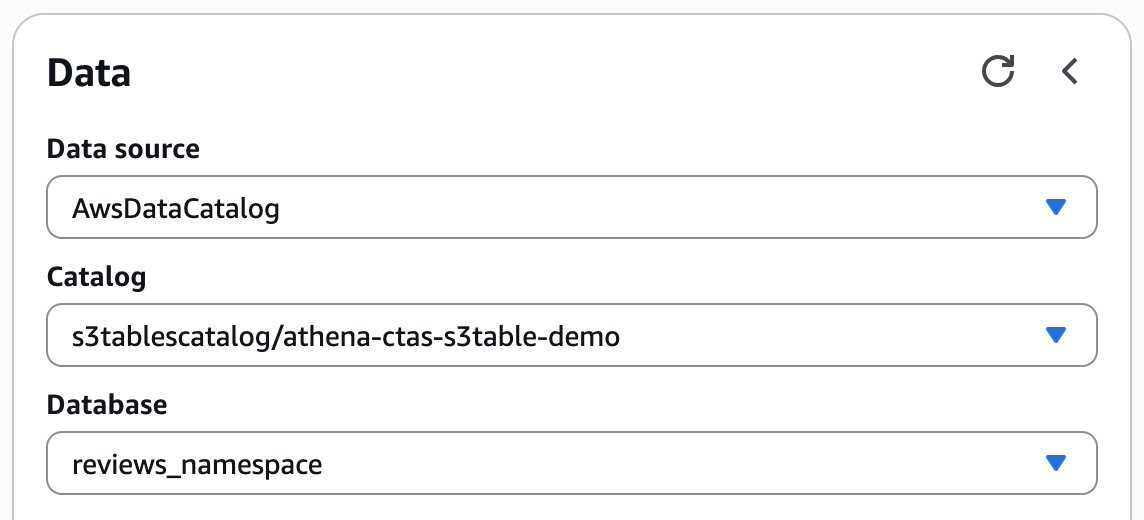
When you enable Integration with AWS analytics services, when creating an S3 table bucket, AWS Glue creates a new catalog called s3tablescatalog in your account’s default Data Catalog specific to your Region. The integration maps the S3 table bucket resources in your account and Region in this catalog.
This configuration makes sure subsequent queries will target your S3 Tables namespace. You’re now ready to create tables using the CTAS functionality.
Create a new S3 table using the customer_reviews table
A table represents a structured dataset consisting of underlying table data and related metadata stored in the Iceberg table format. In the following steps, we transform the customer_reviews table that we created earlier on the Parquet dataset into an S3 table using the Athena CTAS statement. We partition by date using the day() partition transforms from Iceberg.
Run the following CTAS query:
This query creates as S3 table with the following optimizations:
- Parquet format – Efficient columnar storage for analytics
- Day-level partitioning – Uses Iceberg’s
day()transform onreview_datefor fast queries when filtering on dates - Filtered data – Includes only reviews from 2016 onwards to demonstrate selective transformation
You have successfully transformed your Parquet dataset to S3 Tables using a single CTAS statement.
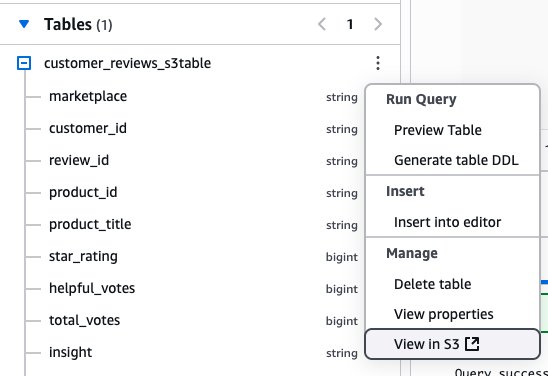
After you create the table, customer_reviews_s3table will appear under Tables in the Athena console. You can also view the table on the Amazon S3 console by choosing the options menu (three vertical dots) next to the table name and choosing View in S3.
Run a preview query to confirm the data transformation:
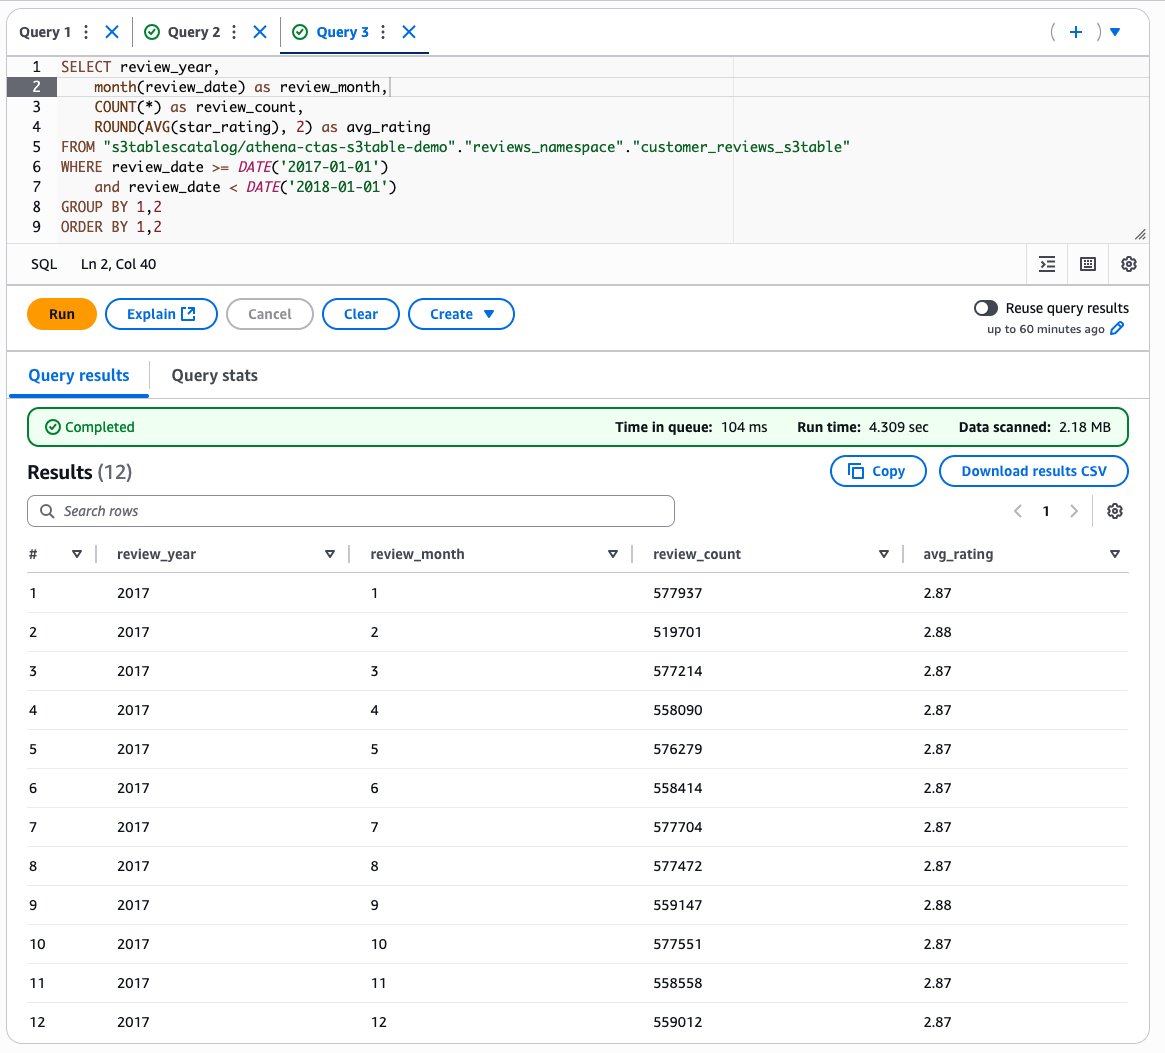
Next, let’s analyze monthly review trends:
The following screenshot shows our output.
ACID operations on S3 Tables
Athena supports standard SQL DML operations (INSERT, UPDATE, DELETE and MERGE INTO) on S3 Tables with full ACID transaction guarantees. Let’s demonstrate these capabilities by adding historical data and performing data quality checks.
Insert more data into the table using INSERT
Use the following query to insert review data from 2014 and 2015 that wasn’t included in the initial CTAS operation:
Check which years are now present in the table:
The following screenshot shows our output.
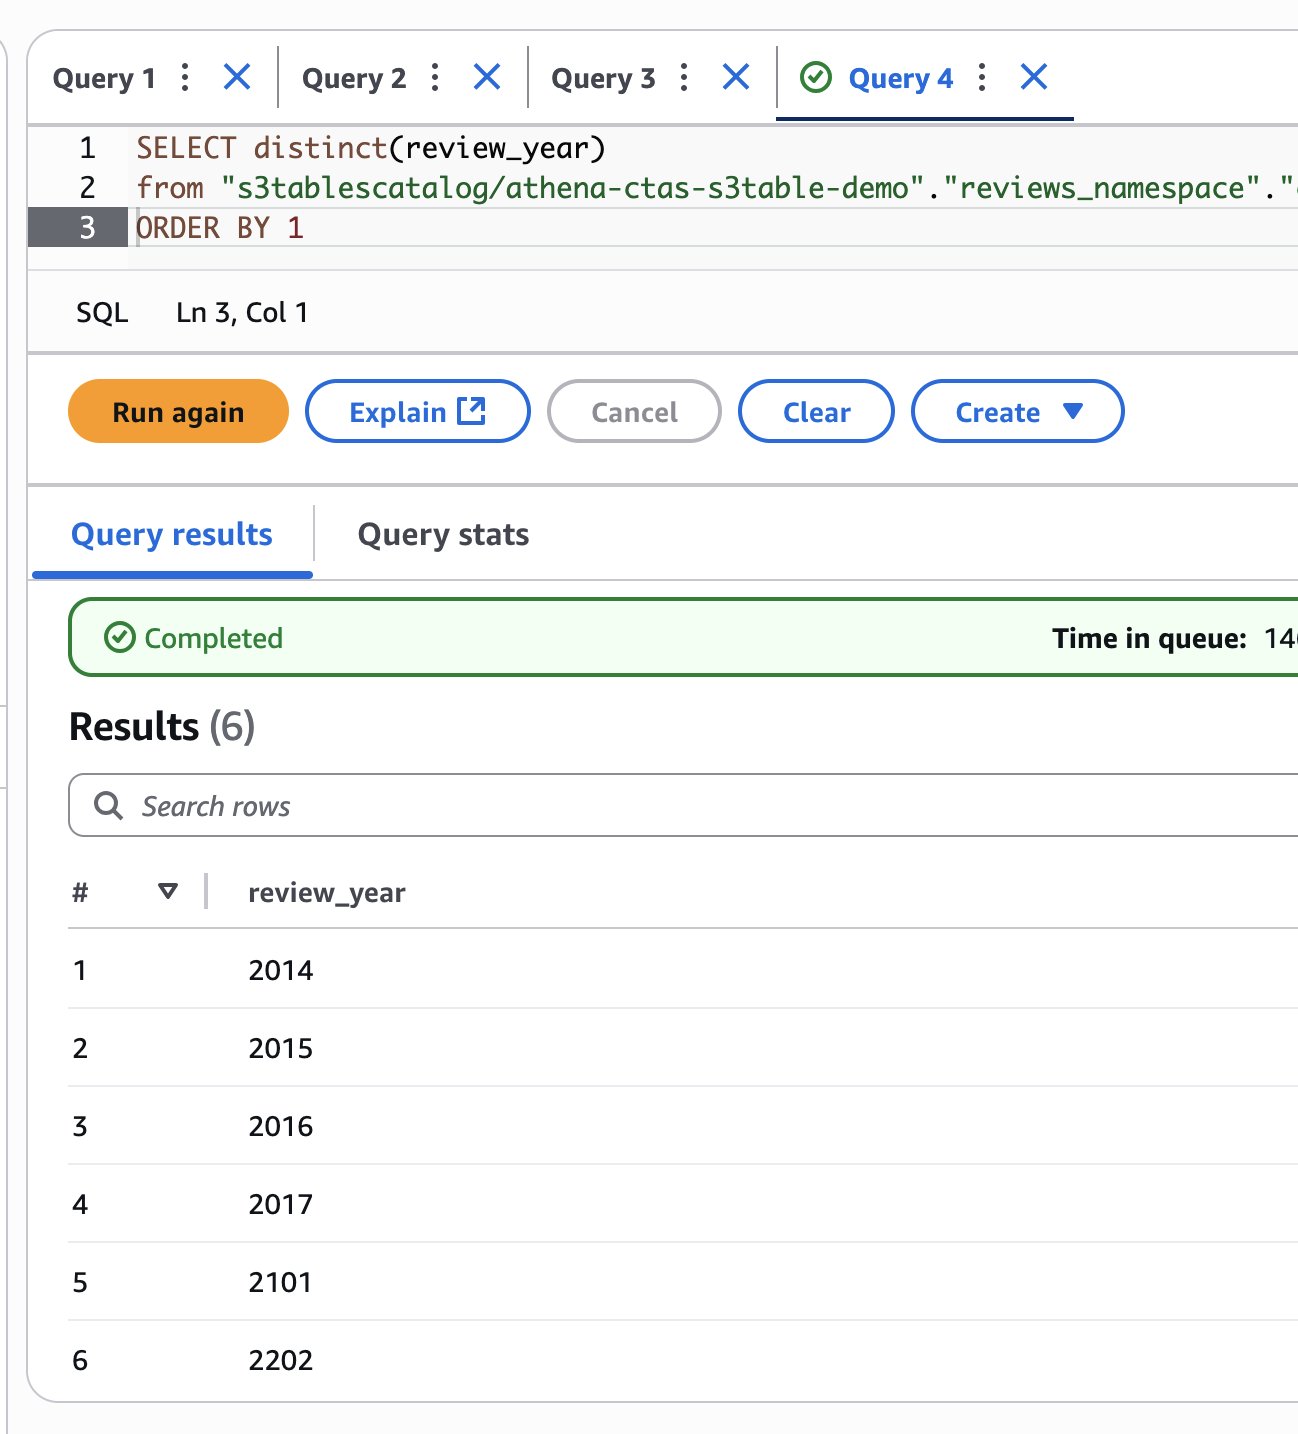
The results show that you have successfully added 2014 and 2015 data. However, you might also notice some invalid years like 2101 and 2202, which appear to be data quality issues in the source dataset.
Clean invalid data using DELETE
Remove the records with incorrect years using the S3 Tables DELETE capability:
Confirm the invalid records have been removed.
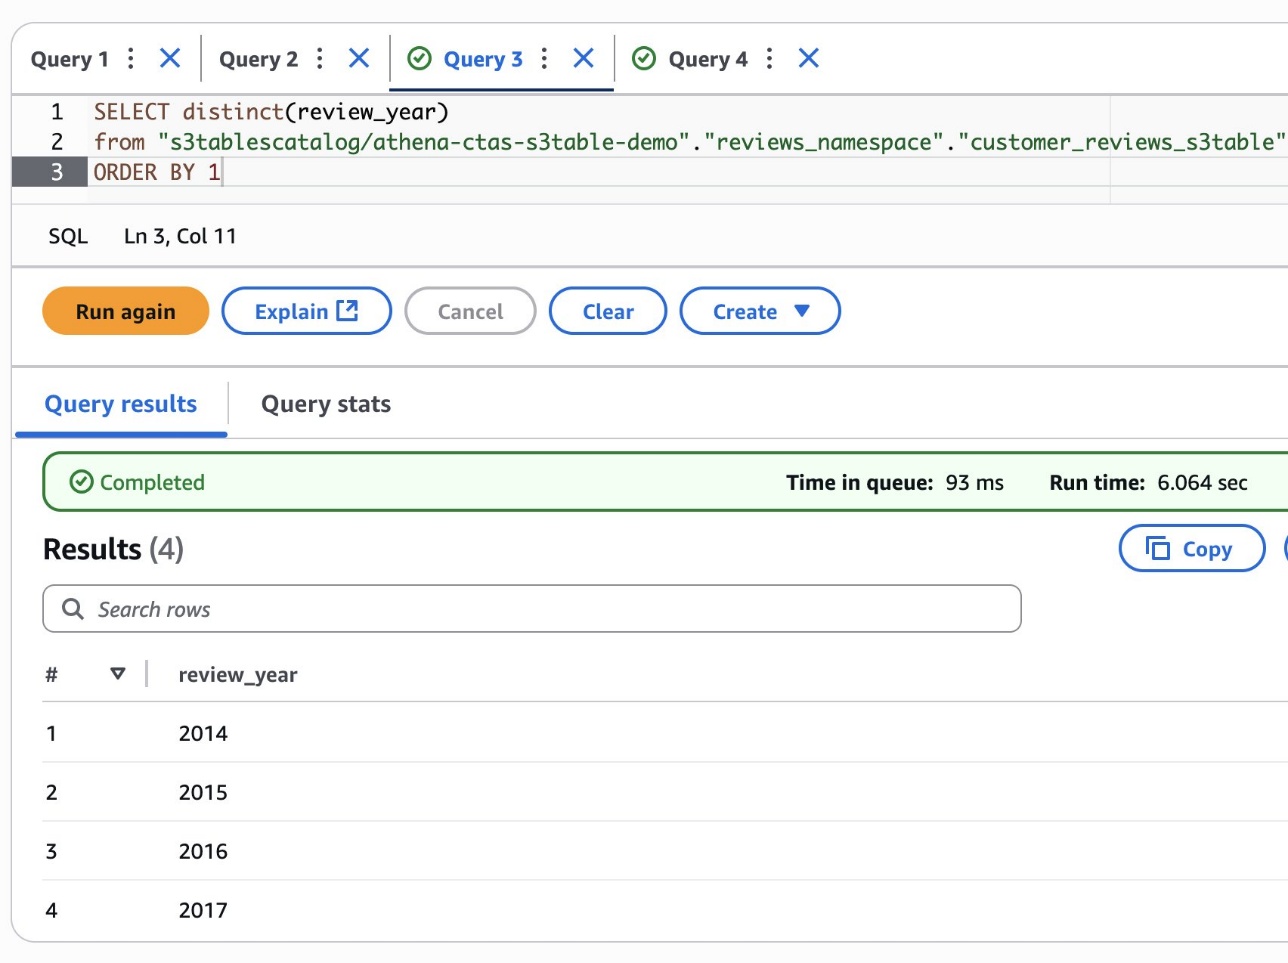
Update product categories using UPDATE
Let’s demonstrate the UPDATE operation with a business scenario. Imagine the company decides to rebrand the Movies_TV product category to Entertainment_Media to better reflect customer preferences.
First, examine the current product categories and their record counts:
You should see a record with product_category as Movies_TV with approximately 5,690,101 reviews. Use the following query to update all Movies_TV records to the new category name:
Verify the category name change while confirming the record count remains the same:
The results now show Entertainment_Media with the same record count (5,690,101), confirming that the UPDATE operation successfully modified the category name while preserving data integrity.
These examples demonstrate transactional support in S3 Tables through Athena. Combined with automated table maintenance, this helps you build scalable, transactional data lakes more efficiently with minimal operational overhead.
Additional transformation scenarios using CTAS
The Athena CTAS functionality supports multiple transformation paths to S3 Tables. The following scenarios demonstrate how organizations can use this capability for various data modernization needs:
- Convert from various data formats – Athena can query data in a wide range of formats as well as federated data sources, and you can convert these queryable sources to an S3 table using CTAS. For example, to create an S3 table from a federated data source, use the following query:
- Transform between S3 tables for optimized analytics – Organizations often need to create derived tables from existing S3 tables optimized for specific query patterns. For example, consider a table containing detailed customer reviews that’s partitioned by product category. If your analytics team frequently queries by date ranges, you can use CTAS to create a new S3 table partitioned by date for significantly better performance on time-based queries. For example, the following query creates an aggregated analytics S3 table:
- Transform from self-managed open table formats – Organizations maintaining their own Iceberg tables can transform them into S3 tables to take advantage of automatic optimization and reduce operational overhead:
- Combine multiple source tables – Organizations often need to consolidate data from multiple tables into a single table for simplified analytics. This approach can help reduce query complexity and improve performance by pre-joining related datasets. The following query joins multiple tables using CTAS to create an S3 table:
These scenarios demonstrate the flexibility of Athena CTAS for various data modernization needs, from simple format conversions to complex data consolidation projects.
Clean up
To avoid ongoing charges, clean up the resources created during this walkthrough. Complete these steps in the specified order to facilitate proper resource deletion. You might need to add respective delete permissions for databases, table buckets, and tables if your IAM user or role doesn’t already have them.
- Delete the S3 table created through CTAS:
- Remove the namespace from the table bucket:
- Delete the table bucket.
- Remove the database and table created for the synthetic dataset:
- Delete any created IAM roles or policies.
- Delete the Athena query result location in Amazon S3 if you stored results in an S3 location.
Conclusion
This post demonstrated how the CTAS functionality in Athena simplifies data transformation to S3 Tables using standard SQL statements. We covered the complete transformation process, including format conversions, ACID operations, and various data transformation scenarios. The solution delivers simplified data transformation through single SQL statements, automatic maintenance, and seamless integration of S3 Tables with AWS analytics services and third-party tools. Organizations can modernize their data infrastructure while achieving enterprise-grade performance.
To get started, begin by identifying datasets that could benefit from optimization or transformation, then refer to Working with Amazon S3 Tables and table buckets and Register S3 table bucket catalogs and query Tables from Athena to implement the transformation patterns demonstrated in this walkthrough. The combination of the serverless capabilities of Athena with the automatic optimizations in S3 Tables can provide a powerful foundation for modern data analytics.
About the authors
 Pathik Shah is a Sr. Analytics Architect on Amazon Athena. He joined AWS in 2015 and has been focusing in the big data analytics space since then, helping customers build scalable and robust solutions using AWS Analytics services.
 Aritra Gupta is a Senior Technical Product Manager on the Amazon S3 team at Amazon Web Services. He helps customers build and scale data lakes. Based in Seattle, he likes to play chess and badminton in his spare time.
Hashimoto: We rewrote the Ghostty GTK application
Post Syndicated from jzb original https://lwn.net/Articles/1033954/
Mitchell Hashimoto has written a blog
post about “fully embracing the GObject type system
” with a
rewrite of the GTK version of Ghostty:
In addition to memory management [improvements], we can now more
easily create custom GTK widgets. This let us fully embrace modern GTK
UI technologies such as Blueprint. For example, here is our terminal
window Blueprint file. This has already led to more easily introducing
GUI features like a new GTK titlebar tabs option, an animated border
on bell, etc.
The rewrite is now the default if one builds Ghostty from source,
and will be included in the 1.2 release that is expected in the next
few weeks. LWN covered
Ghostty in January.
Comic for 2025.08.15 – Ziiiiiiiiip
Post Syndicated from Explosm.net original https://explosm.net/comics/ziiiiiiiiip
New Cyanide and Happiness Comic
$150 for this Fanvil Video Intercom Kit? Here’s What You Need to Know
Post Syndicated from Crosstalk Solutions original https://www.youtube.com/watch?v=E1pFWyIzPsE
AWS named as a Leader in 2025 Gartner Magic Quadrant for Strategic Cloud Platform Services for 15 years in a row
Post Syndicated from Channy Yun (윤석찬) original https://aws.amazon.com/blogs/aws/aws-named-as-a-leader-in-2025-gartner-magic-quadrant-for-strategic-cloud-platform-services-for-15-years-in-a-row/
On August 4, 2025, Gartner published its Gartner Magic Quadrant for Strategic Cloud Platform Services (SCPS). Amazon Web Services (AWS) is the longest-running Magic Quadrant Leader, with Gartner naming AWS a Leader for the fifteenth consecutive year.
In the report, Gartner once again placed AWS highest on the “Ability to Execute” axis. We believe this reflects our ongoing commitment to giving customers the broadest and deepest set of capabilities to accelerate innovation as well as unparalleled security, reliability, and performance they can trust for their most critical applications.
Here is the graphical representation of the 2025 Magic Quadrant for Strategic Cloud Platform Services.
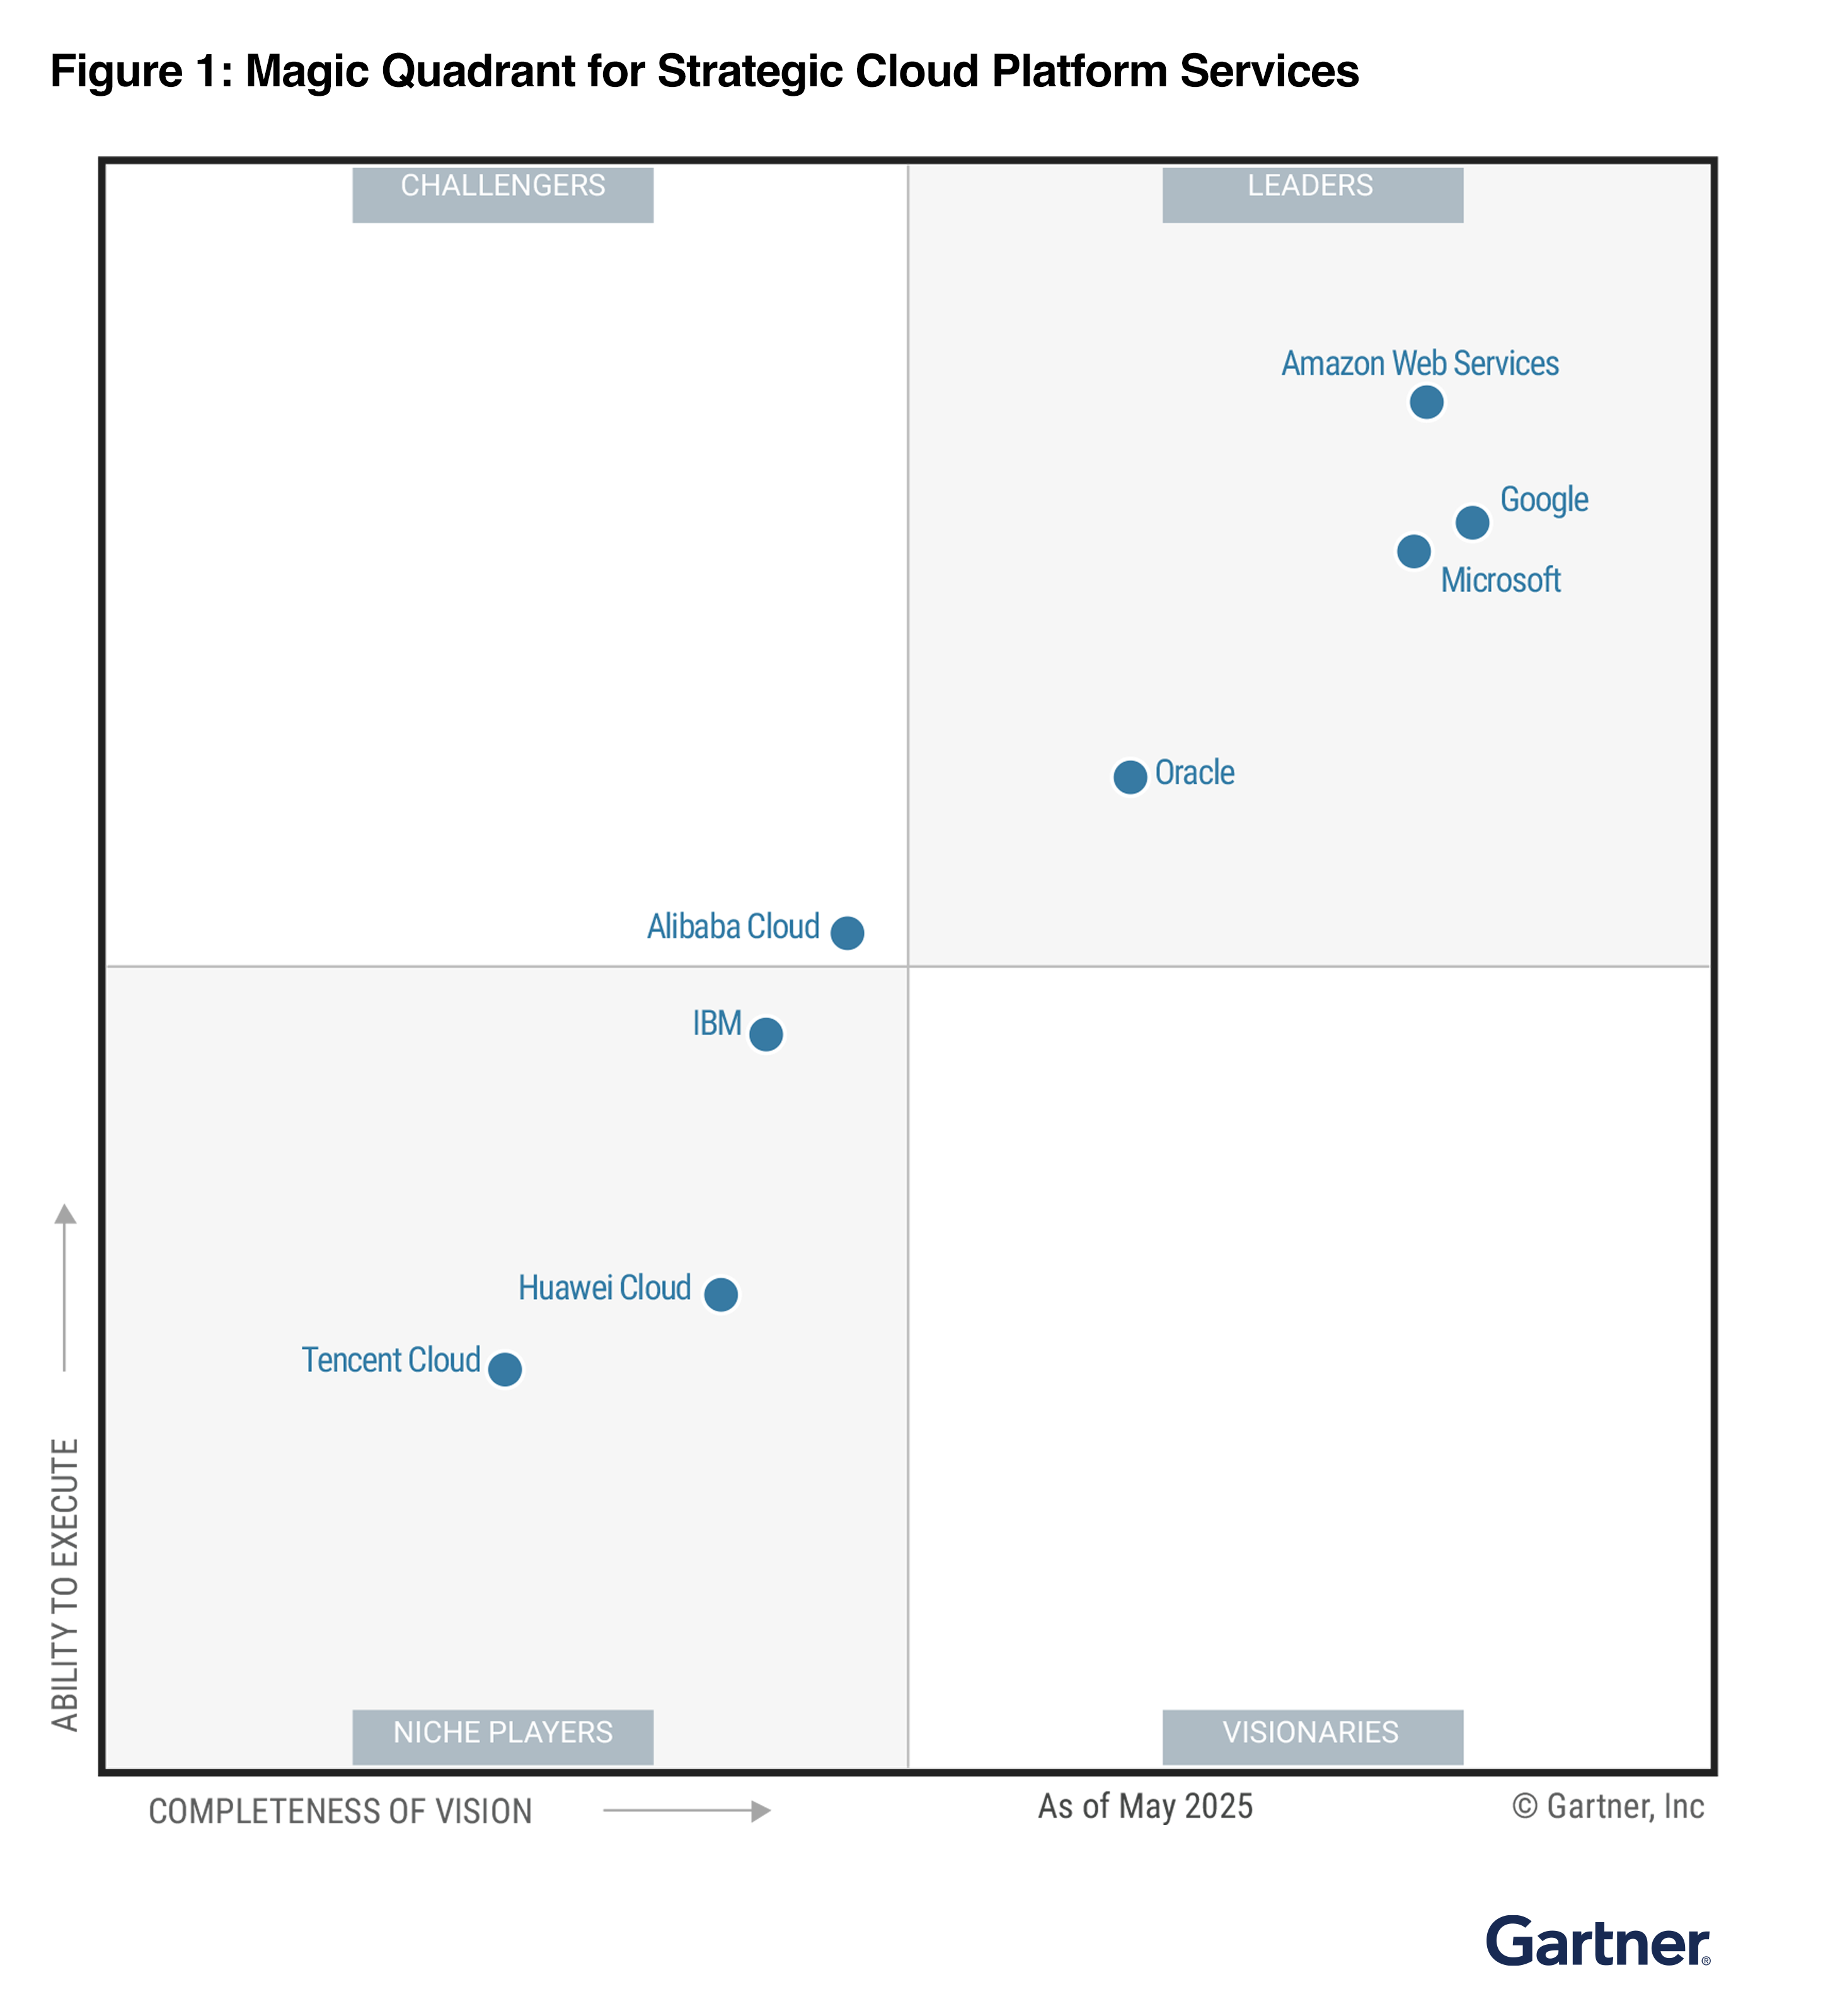
Gartner recognized AWS strengths as:
- Largest cloud community – AWS has built a strong global community of cloud professionals, providing significant opportunities for learning and engagement.
- Cloud-inspired silicon – AWS has used its cloud computing experience to develop custom silicon designs, including AWS Graviton, AWS Inferentia, and AWS Trainium, which enable tighter integration between hardware and software, improved power efficiency, and greater control over supply chains.
- Global scale and operational execution – AWS’s significant share of global cloud market revenue has enabled it to build a larger and more robust network of integration partners than some other providers in this analysis, which in turn helps organizations successfully adopt cloud.
The most common feedback I hear from customers is that AWS has the largest and most dynamic cloud community, making it easy to ask questions and learn from millions of active customers and tens of thousands of partners globally. We recently launched our community hub, AWS Builder Center to connect directly with AWS Heroes and AWS Community Builders. You can also explore and join AWS User Groups and AWS Cloud Clubs in a city near you.
We have also focused on facilitating the digital transformation of enterprise customers through a number of enterprise programs, such as the AWS Migration Acceleration Program. Using generative AI on migration and modernization, we introduced AWS Transform, the first agentic AI service developed to accelerate enterprise modernization of mission-critical business workloads such as .NET, mainframe, and VMware.
Access the complete full Gartner report to learn more. It outlines the methodology and evaluation criteria used to develop their assessments of each cloud service provider included in the report. This report can serve as a guide when choosing a cloud provider that helps you innovate on behalf of your customers.
— Channy
Gartner does not endorse any vendor, product or service depicted in its research publications and does not advise technology users to select only those vendors with the highest ratings or other designation. Gartner research publications consist of the opinions of Gartner’s research organization and should not be construed as statements of fact. Gartner disclaims all warranties, expressed or implied, with respect to this research, including any warranties of merchantability or fitness for a particular purpose.
GARTNER is a registered trademark and service mark of Gartner and Magic Quadrant is a registered trademark of Gartner, Inc. and/or its affiliates in the U.S. and internationally and are used herein with permission. All rights reserved.
ICE & Mass Deportation #lastweektonight
Post Syndicated from LastWeekTonight original https://www.youtube.com/shorts/VPtAWwRBHUc
Celebrating 10 years of Amazon Aurora innovation
Post Syndicated from Sébastien Stormacq original https://aws.amazon.com/blogs/aws/celebrating-10-years-of-amazon-aurora-innovation/
Ten years ago, we announced the general availability of Amazon Aurora, a database that combined the speed and availability of high-end commercial databases with the simplicity and cost-effectiveness of open source databases.
As Jeff described it in its launch blog post: “With storage replicated both within and across three Availability Zones, along with an update model driven by quorum writes, Amazon Aurora is designed to deliver high performance and 99.99% availability while easily and efficiently scaling to up to 64 TiB of storage.”
When we started developing Aurora over a decade ago, we made a fundamental architectural decision that would change the database landscape forever: we decoupled storage from compute. This novel approach enabled Aurora to deliver the performance and availability of commercial databases at one-tenth the cost.
This is one of the reasons why hundreds of thousands of AWS customers choose Aurora as their relational database.
Today, I’m excited to invite you to join us for a livestream event on August 21, 2025, to celebrate a decade of Aurora database innovation.
A brief look back at the past
Throughout the evolution of Aurora, we’ve focused on four core innovation themes: security as our top priority, scalability to meet growing workloads, predictable pricing for better cost management, and multi-Region capabilities for global applications. Let me walk you through some key milestones in the Aurora journey.
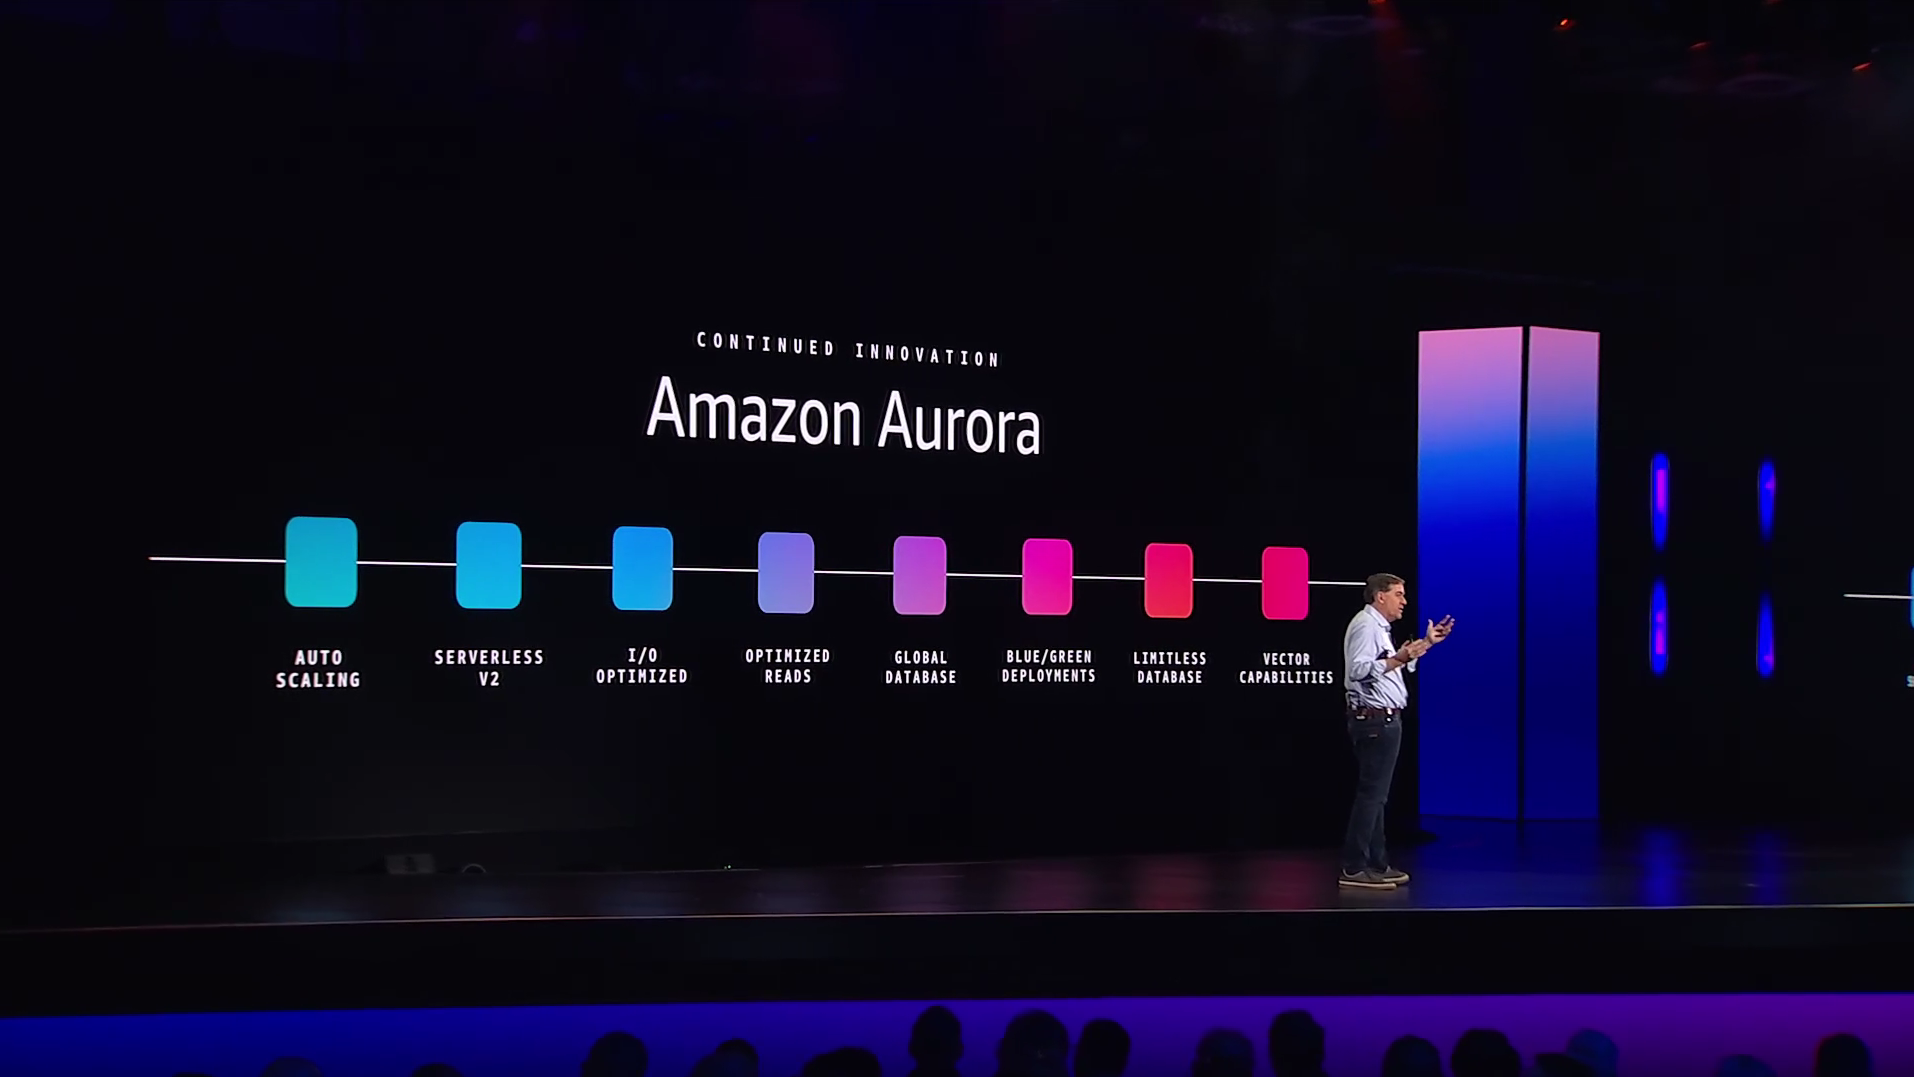
We previewed Aurora at re:Invent 2014, and made it generally available in July 2015. At launch, we presented Aurora as “a new cost-effective MySQL-compatible database engine.”
In June 2016, we introduced reader endpoints and cross-Region read replicas, followed by AWS Lambda integration and the ability to load tables directly from Amazon S3 in October. We added database cloning and export to Amazon S3 capabilities in June 2017 and full compatibility with PostgreSQL in October that year.
The journey continued with the serverless preview in November 2017, which became generally available in August 2018. Global Database launched in November 2018 for cross-Region disaster recovery. We introduced blue/green deployments to simplify database updates, and optimized read instances to improve query performance.
In 2023, we added vector capabilities with pgvector for similarity search for Aurora PostgreSQL, and Aurora I/O-Optimized to provide predictable pricing with up to 40 percent cost savings for I/O-intensive applications. We launched Aurora zero-ETL integration with Amazon Redshift which enables near real-time analytics and ML using Amazon Redshift on petabytes of transactional data from Aurora by removing the need for you to build and maintain complex data pipelines that perform extract, transform, and load (ETL) operations. This year we added Aurora MySQL zero-ETL integration with Amazon Sagemaker, enabling near real-time access of your data in the lakehouse architecture of SageMaker to run a broad range of analytics.
In 2024, we made it as effortless as just one click to select Aurora PostgreSQL as a vector store for Amazon Bedrock Knowledge Bases and launched Aurora PostgreSQL Limitless Database, a serverless horizontal scaling (sharding) capability.
To simplify scaling for customers, we also increased the maximum storage to 128 TiB in September 2020, allowing many applications to operate within a single instance. Last month, we’ve further simplified scaling by doubling the maximum storage to 256 TiB, with no upfront provisioning required and pay-as-you-go pricing based on actual storage used. This enables even more customers to run their growing workloads without the complexity of managing multiple instances while maintaining cost efficiency.
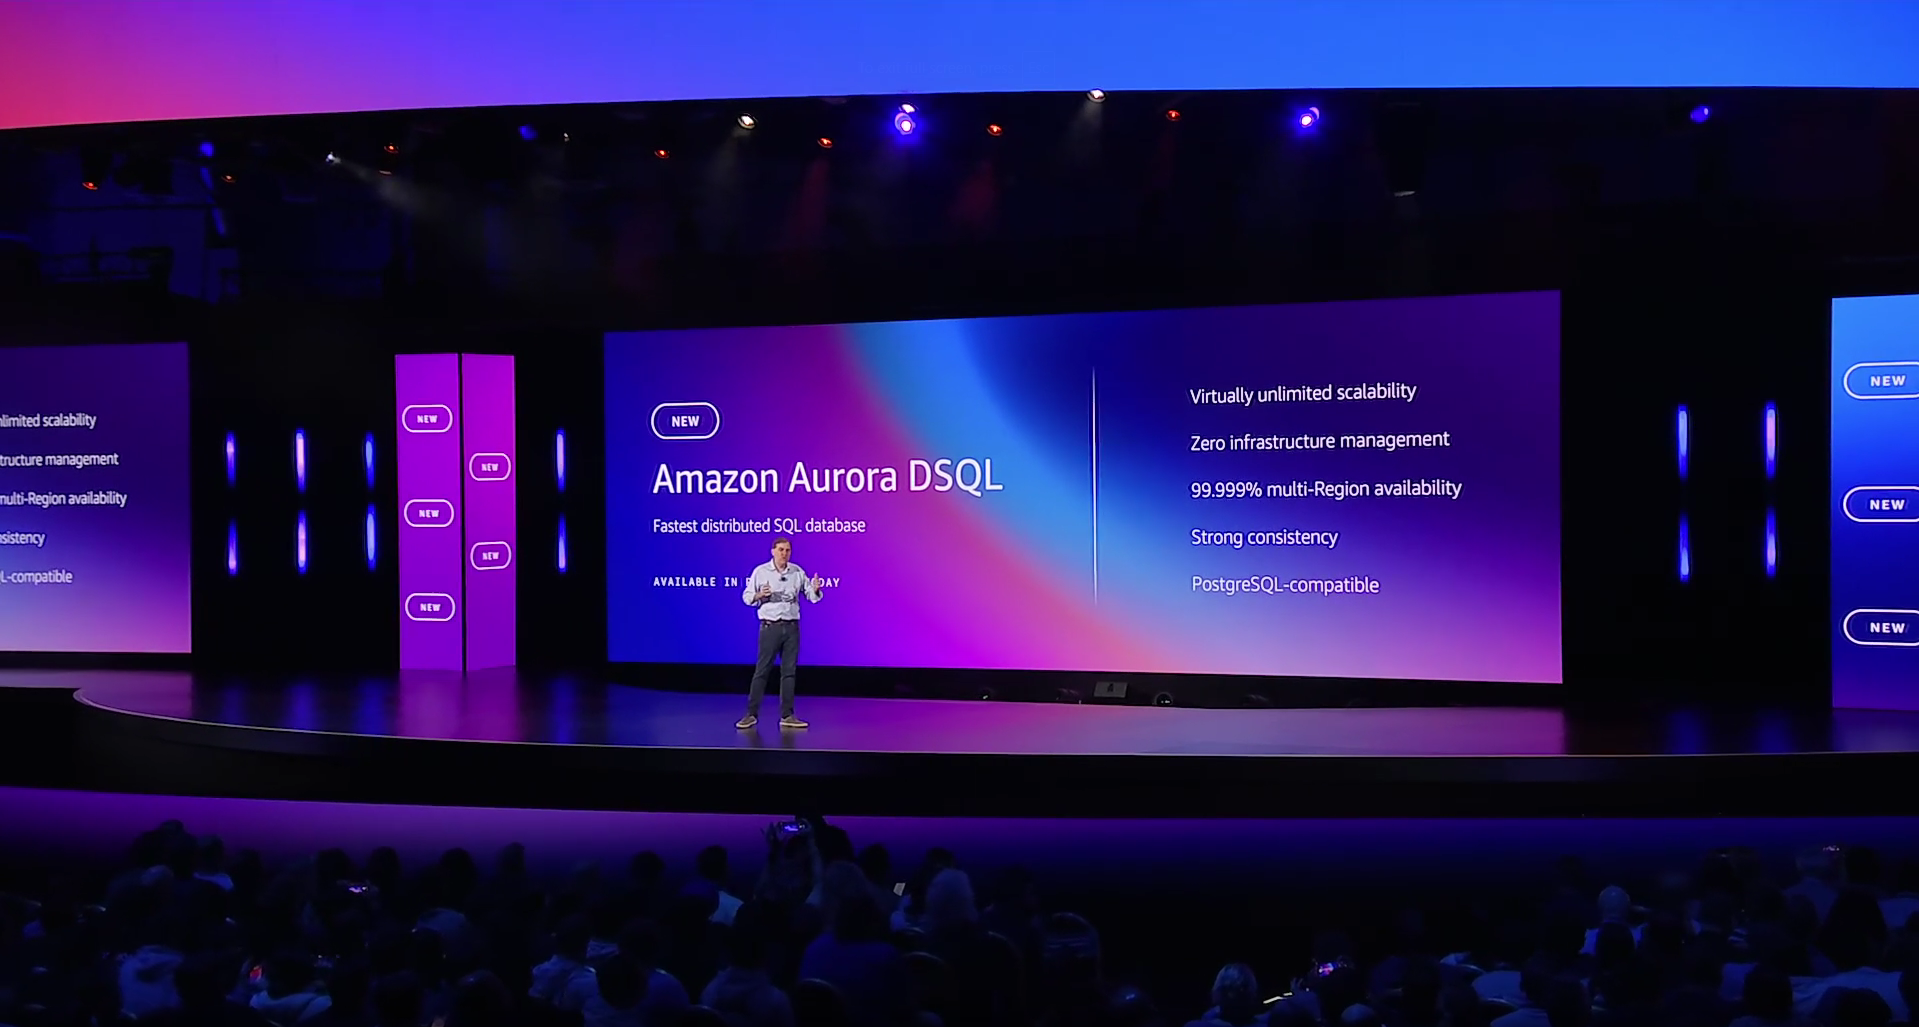
Most recently, at re:Invent 2024, we announced Amazon Aurora DSQL, which became generally available in May 2025. Aurora DSQL represents our latest innovation in distributed SQL databases, offering active-active high availability and multi-Region strong consistency. It’s the fastest serverless distributed SQL database for always available applications, effortlessly scaling to meet any workload demand with zero infrastructure management.
Aurora DSQL builds on our original architectural principles of separation of storage and compute, taking them further with independent scaling of reads, writes, compute, and storage. It provides 99.99% single-Region and 99.999% multi-Region availability, with strong consistency across all Regional endpoints.
And in June, we launched Model Context Protocol (MCP) servers for Aurora, so you can integrate your AI agents with your data sources and services.
Let’s celebrate 10 years of innovation
 By attending the August 21 livestream event, you’ll hear from Aurora technical leaders and founders, including Swami Sivasubramanian, Ganapathy (G2) Krishnamoorthy, Yan Leshinsky, Grant McAlister, and Raman Mittal. You’ll learn directly from the architects who pioneered the separation of compute and storage in cloud databases, with technical insights into Aurora architecture and scaling capabilities. You’ll also get a glimpse into the future of database technology as Aurora engineers share their vision and discuss the complex challenges they’re working to solve on behalf of customers.
The event also offers practical demonstrations that show you how to implement key features. You’ll see how to build AI-powered applications using pgvector, understand cost optimization with the new Aurora DSQL pricing model, and learn how to achieve multi-Region strong consistency for global applications.
The interactive format includes Q&A opportunities with Aurora experts, so you’ll be able to get your specific technical questions answered. You can also receive AWS credits to test new Aurora capabilities.
If you’re interested in agentic AI, you’ll particularly benefit from the sessions on MCP servers, Strands Agents, and how to integrate Strands Agents with Aurora DSQL, which demonstrate how to safely integrate AI capabilities with your Aurora databases while maintaining control over database access.
Whether you’re running mission-critical workloads or building new applications, these sessions will help you understand how to use the latest Aurora features.
Register today to secure your spot and be part of this celebration of database innovation.
To the next decade of Aurora innovation!