Tag Archives: CDNJS

Dogfooding at scale: migrating cdnjs to Cloudflare’s Developer Platform

Post Syndicated from Simona Badoiu original https://blog.cloudflare.com/cdnjs-dev-platform-migration/

As of June 23, 2026, cdnjs, one of the Internet's busiest open-source CDNs, is running exclusively on Cloudflare’s Developer Platform. Along the way, cdnjs surfaced limits in the platform, and the platform grew to meet them.

cdnjs is a free, open-source content delivery network for JavaScript and CSS libraries. Instead of using a bundler or self-hosting jQuery, Bootstrap, or Lodash, you drop a <script> tag pointing to cdnjs.cloudflare.com and the library loads from Cloudflare's edge, instantly, anywhere in the world, with no signup, no API keys, and no rate limits. It's the infrastructure behind a significant portion of “intro to JavaScript” tutorials, CodePen demos, and Stack Overflow answers.

Community-driven, cdnjs is used on roughly 12% of all websites, a 48.3% share of the JavaScript CDN market. It serves an average of 108,000 requests per second, 9 billion per day, across more than 330 Cloudflare data centers, with a 98.6% cache hit rate. Pretty cool, Internet!

In 2011, when bundlers were exotic, npm was barely a year old, and "just drop a <script> tag" was how the web shipped JavaScript, Ryan Kirkman and Thomas Davis built cdnjs as a free, community-run mirror of every popular open-source library. 

Cloudflare stepped in to host it free of charge months later, and took over project maintenance in 2019. Back then, Cloudflare didn't have a mature Developer Platform that could fully sustain the entire cdnjs ecosystem. Fifteen years and a lot of building blocks later, the platform is mature enough to run cdnjs end to end, on Workers, Workflows, D1, Queues, Workers Cache, R2, KV, and Containers.

Why cdnjs has 9 billion requests a day 

The web has changed beyond recognition from those days. We have ES Modules (ESM), the standardized import / export syntax browsers understand natively. We have import maps, Vite, Bun, Turbopack. We have AI assistants that scaffold entire apps in seconds. Bundlers are everywhere. So why does a CDN for <script> tags still serve 9 billion requests a day?

One reason: LLMs love cdnjs. When ChatGPT, Claude, or Cursor scaffold a quick HTML demo, they reach for cdnjs because their training data is full of it. There have been 15 years of blog posts, GitHub READMEs, tutorial sites, and Q&A threads pointing to cdnjs.cloudflare.com. The URL pattern is consistent and versions are immutable — exactly the kind of dependency a model can produce reliably without hallucinating.

Every file on cdnjs has an SRI hash (we're still working on ensuring all the existing stored hashes match reality due to bugs in the old system), mirrors are auditable, and the whole project is open source. In a world increasingly worried about supply-chain attacks, an immutable, hash-verified mirror of well-known libraries is indispensable.

And it's free, forever, for everyone. No API keys. No rate limits. No "sign up to continue." That's a rare thing on today's Internet, and it's worth protecting.

Why we migrated

We didn't migrate because cdnjs was slow. We migrated because we want to keep improving it.

The previous architecture served users well: 98% cache hit, billions of requests, no outages. But internally, shipping anything new or fixing existing issues in how packages were processed was getting harder. Making a change meant coordinating deployments across GCP Functions, a VM, and Cloudflare. Observability was painful too.

The pain points  

In 2020, we migrated cdnjs to serverless, moving file serving onto Cloudflare Workers and KV, with a bare-metal origin as fallback. That change dramatically improved resilience and scalability, and let us pre-compress every asset with Brotli and gzip for smaller, faster responses, but only on the serving side.

The publishing side — the pipeline that watches npm and GitHub for new library versions, downloads them, processes them, and writes the results so cdnjs can serve them — stayed on Google Cloud Platform (GCP). At the time, Cloudflare Workers were designed for fast, short-lived HTTP requests; they didn't yet have the building blocks for a long-running, multi-step pipeline that fetches large tarballs, runs CPU-heavy compression, and orchestrates work over hours. Workflows, Queues, Durable Objects, R2, and Containers didn't exist yet.

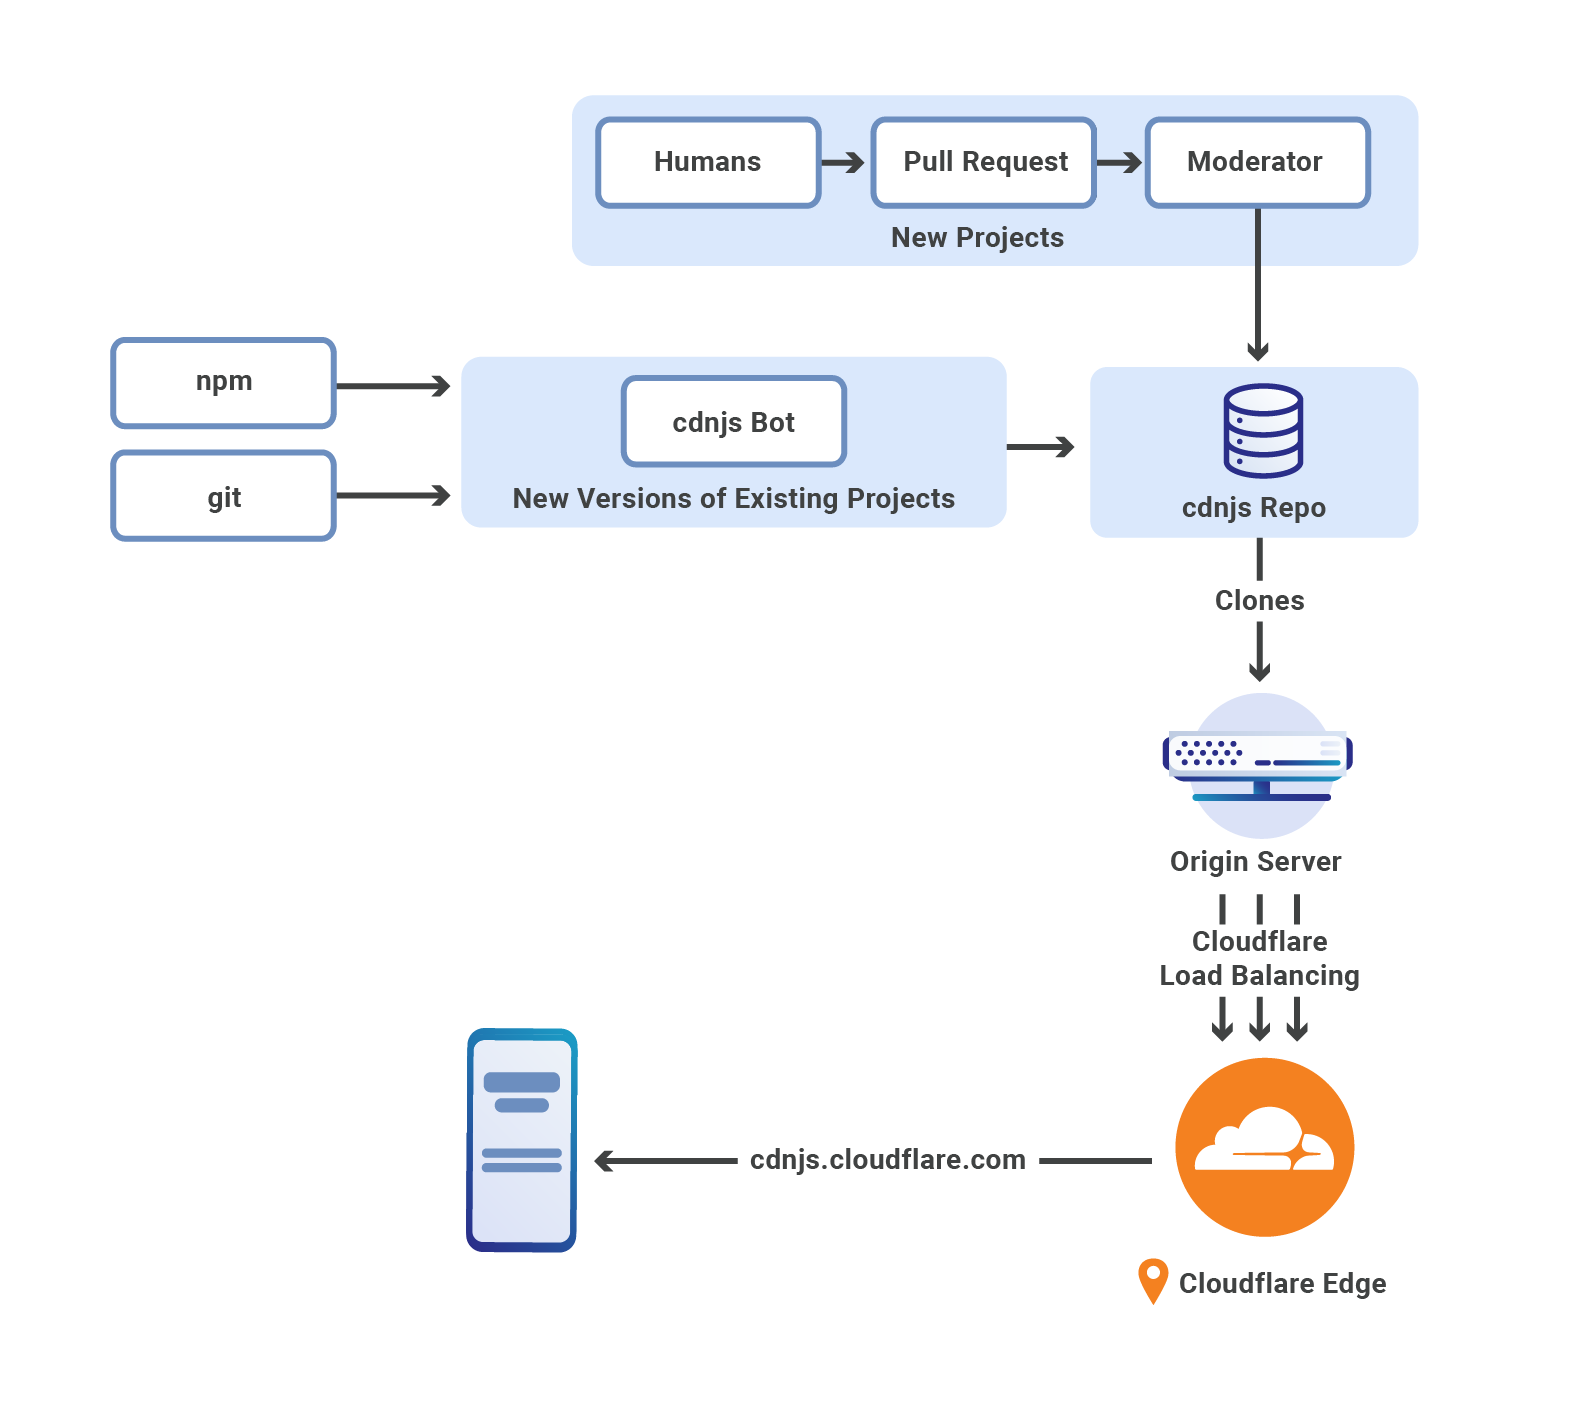
So we built the publishing bot on what was available: a chain of GCP Functions, a VM running git-sync, and a GitHub repository as the source of truth. It worked, but six years later, that architecture was showing its age. Here's a diagram of the previous architecture:


The architecture had five pain points. The one that hurt most was observability: debugging meant stitching logs together by hand. We'll start there.

  1. No shared trace
    A single package update could pass through Cloud Functions, Google Cloud Storage (GCS) object events, Pub/Sub topics, a git-sync VM, and Workers KV before a file reached a user. None of those systems shared a correlation ID. GCP Logging held one half of the story, Cloudflare Logpush held the other, and the two had no common key to join on.

    The problem wasn't outright failure, it was partial success. A version that processed cleanly, wrote to KV, and then silently failed to land in the GitHub repo would serve fine for weeks until someone noticed the two stores had diverged. There was no alert for that. There couldn't be, because nothing in the system knew the full pipeline state.

  2. Split-brain storage
    Files lived in two places at once: Workers KV at the edge (with a bare-metal origin as fallback) and a GitHub repository as the source of truth. The ingestion pipeline wrote to both at the end of every run. Neither was authoritative, and when they drifted, there was no clean way to reconcile them.
  3. Pipeline glued together with object events
    The ingestion pipeline was a chain of small GCP Cloud Functions, each doing one step and handing off to the next through shared storage. One function fetched the package's release archive from npm and dropped it in a bucket. The bucket firing a "new file" event triggered the next function, which unpacked it and wrote the results somewhere else, triggering the next, and so on. Storage was doing double duty as a message queue, with no dead-letter queue, no backlog visibility, and no clean replay when a step failed.
  4. 26 functions for 26 letters
    Just checking npm for updates required 26 Cloud Functions, one per letter of the alphabet. Each shard had its own deployment and its own logs, and the only way to know if the fleet was healthy was to check all 26.
  5. The GitHub repo GitHub couldn't serve
    A separate VM ran git-sync, mirroring every processed file into cdnjs/cdnjs. Years of releases pushed it past 1.1TB of packed storage, large enough that GitHub's own archive service refused to generate tarballs or zip downloads for it. Forking became impractical, clones were slow, and the .gitignore had grown to 274 hand-curated entries blocking broken or weirdly-versioned releases. It was a documented graveyard of everything the pipeline couldn't reasonably reject upstream.

    A genuine thank you to the GitHub team for hosting this giant for over a decade. They bore with us through years of storage growth, and the project wouldn't have survived without them.

    A quieter benefit that came with the migration is having fewer moving parts to secure. Cloud Functions, a git-sync VM, container images, GCS buckets, service-account keys — every one of those was a thing to secure, patch, and audit. Retiring the pipeline closed all of the recently opened cdnjs vulnerabilities.

How we re-built it

The new cdnjs architecture runs entirely on Cloudflare’s Developer Platform.

R2 is the single source of truth for file content. It has no practical size limit, so the files that couldn't fit in KV before, like source maps, big bundles, and font packs, now live alongside everything else. As a bonus, the S3 API makes the entire cdnjs catalog accessible to any S3 client. Maintain a mirror? Open an issue on the cdnjs repository and we'll set you up with read-only credentials.

KV stores only metadata now: package info, version lists, SRI hashes. KV is built for high read volume with infrequent writes, which is exactly the shape of metadata access.

In front of the Worker sits Workers Cache, a tiered cache Cloudflare launched this year. Before, we relied on a separate internal caching layer between the edge and the Worker. That layer is gone now, replaced by one owned by the Developer Platform, the same platform that runs the rest of cdnjs. One less moving part!

The new architecture also extends a long-standing partnership. DigitalOcean has hosted the cdnjs website for years as a sponsor; now it hosts the storage too. Every file published to R2 is mirrored to DigitalOcean Spaces: architecturally a disaster-recovery copy, operationally also a live fallback. The serving worker reads through to it whenever R2 can’t return a file. The chain is cache → R2 → DigitalOcean, so R2 having a bad day doesn't take cdnjs down. A Cloudflare-hosted origin still sits in the chain during the transition, but it will retire once the GitHub backfill lands in R2.

The ingestion pipeline is built on Cloudflare Workflows. Every ten minutes, a cron job triggers PackageUpdatesWorkflow, which checks npm and GitHub for new versions. For each new version found, it spawns a DownloadPackageWorkflow that fetches the tarball into R2, then a ProcessingWorkflow per file that extracts, minifies, and compresses. Finally, PublishingWorkflow writes the results to R2 and KV and updates the Algolia search index.

Because Workflows provides durable execution, the state of each step is preserved. If anything fails — a network timeout, a compression error — the workflow resumes from the last successful step.

The trickier piece is how we glue Workflows to the external compression container. We pre-compress text-based files to streamline the delivery process. But compression is too CPU-intensive for a Worker, so we hand it off to Cloudflare Containers, wait for compression to complete, and then pick up where we left off.

The pipeline has two kinds of waiting:

Per file: Each ProcessingWorkflow writes the uncompressed file to an R2 bucket, sends a job to a Queue, and hibernates. A Rust compression service running in the container picks it up, compresses it, and writes the result to another bucket. An R2 event notification wakes the workflow up so it can continue.

Per package: The parent workflow needs to wait for all its file children before moving on to publish. A package with thousands of files means thousands of children running in parallel. We use a small Durable Object as a counter: a parent increments on each child it spawns, children decrement when they finish. The parent wakes up when the counter reaches zero.

An overview of the new architecture, with R2 as the source of truth and Workflows running the pipeline:

Pushing the limits

Designing the new architecture was one challenge. Migrating the existing catalog into it, without disturbing a single file already in the wild, was another.

We'd actually tried this once before and had to roll back. The plan, back then, was to re-process old packages and write the results directly to R2, but the regenerated files didn't byte-match what KV had been serving. Minifiers and compressors aren't fully deterministic across versions, so the new outputs were correct but had different SRI hashes. For a CDN where users pin those hashes in their HTML, that's a serving break. So we rolled back, and now, we migrated the existing content from KV to R2 as-is instead of regenerating it.

That decision shifted the problem from "re-process millions of files" to "copy millions of files between accounts, without missing any." And that's where we ran into the Workers subrequest limit, capped at 1,000 per invocation on paid plans. A package with thousands of files would burn through it in one go. Parallelizing didn't help, since every Worker hits the same ceiling. So we sharded the migration by package name and fanned the work out across many invocations via Queues, whose at-least-once delivery guarantee meant no package could silently fall out of the migration.

We hit two platform limits during the migration: 1,000 subrequests per Worker invocation and 1,024 steps per Workflow. Instead of just working around them, we asked the Workers and Workflows teams to raise them — which they did. Subrequests now go up to 10 million on paid plans; Workflows now default to 10,000 steps, configurable to 25,000.

The cdnjs pipeline runs on the same building blocks anyone can use: Workers, Workflows, R2, KV, Queues, Containers, and Durable Objects. The limits we hit are limits we lifted for everyone. If the Cloudflare Developer Platform can serve 9 billion requests a day and publish packages with hundreds of thousands of compressed, minified files, it can probably run whatever you're building.

What’s next

There's an obvious next question hiding in all of this: could cdnjs also serve modern, browser-native ES modules? The same packages, transformed on publish, ready to import without a bundler. The architecture doesn't rule it out. The Workflows-plus-Containers pattern that pre-compresses files today would work just as well for transforming them. We're not committing to it, but it's the kind of thing that's now possible to consider, which wasn't true a year ago.

git commit -m "with love" --author="cdnjs team"

We follow every open issue on GitHub and we want your feedback. Don't hesitate to contribute and help make the Internet better for everyone.
Automatically replacing polyfill.io links with Cloudflare’s mirror for a safer Internet

Post Syndicated from Matthew Prince original https://blog.cloudflare.com/automatically-replacing-polyfill-io-links-with-cloudflares-mirror-for-a-safer-internet


polyfill.io, a popular JavaScript library service, can no longer be trusted and should be removed from websites.

Multiple reports, corroborated with data seen by our own client-side security system, Page Shield, have shown that the polyfill service was being used, and could be used again, to inject malicious JavaScript code into users’ browsers. This is a real threat to the Internet at large given the popularity of this library.

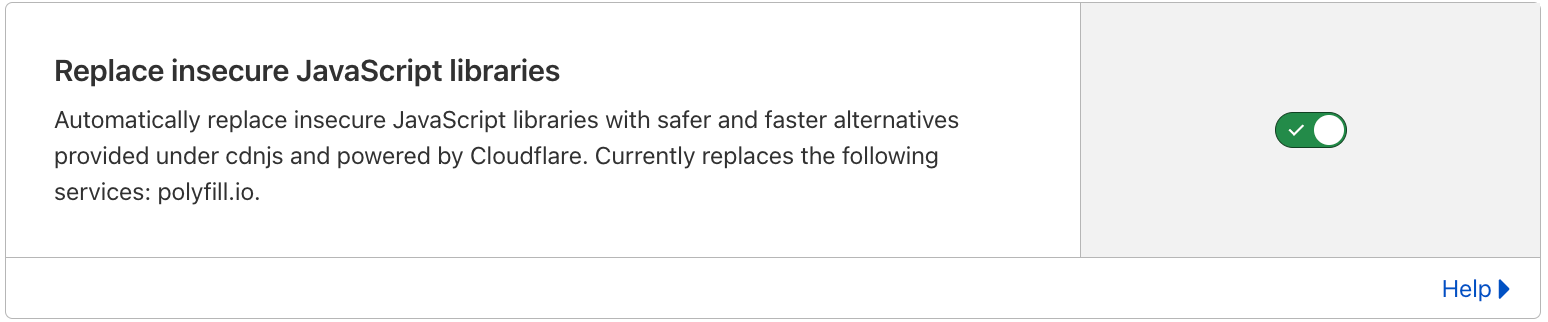
We have, over the last 24 hours, released an automatic JavaScript URL rewriting service that will rewrite any link to polyfill.io found in a website proxied by Cloudflare to a link to our mirror under cdnjs. This will avoid breaking site functionality while mitigating the risk of a supply chain attack.

Any website on the free plan has this feature automatically activated now. Websites on any paid plan can turn on this feature with a single click.

You can find this new feature under Security ⇒ Settings on any zone using Cloudflare.

Contrary to what is stated on the polyfill.io website, Cloudflare has never recommended the polyfill.io service or authorized their use of Cloudflare’s name on their website. We have asked them to remove the false statement and they have, so far, ignored our requests. This is yet another warning sign that they cannot be trusted.

If you are not using Cloudflare today, we still highly recommend that you remove any use of polyfill.io and/or find an alternative solution. And, while the automatic replacement function will handle most cases, the best practice is to remove polyfill.io from your projects and replace it with a secure alternative mirror like Cloudflare’s even if you are a customer.

You can do this by searching your code repositories for instances of polyfill.io and replacing it with cdnjs.cloudflare.com/polyfill/ (Cloudflare’s mirror). This is a non-breaking change as the two URLs will serve the same polyfill content. All website owners, regardless of the website using Cloudflare, should do this now.

How we came to this decision

Back in February, the domain polyfill.io, which hosts a popular JavaScript library, was sold to a new owner: Funnull, a relatively unknown company. At the time, we were concerned that this created a supply chain risk. This led us to spin up our own mirror of the polyfill.io code hosted under cdnjs, a JavaScript library repository sponsored by Cloudflare.

The new owner was unknown in the industry and did not have a track record of trust to administer a project such as polyfill.io. The concern, highlighted even by the original author, was that if they were to abuse polyfill.io by injecting additional code to the library, it could cause far reaching security problems on the Internet affecting several hundreds of thousands websites. Or it could be used to perform a targeted supply-chain attack against specific websites.

Unfortunately, that worry came true on June 25, 2024 as the polyfill.io service was being used to inject nefarious code that, under certain circumstances, redirected users to other websites.

We have taken the exceptional step of using our ability to modify HTML on the fly to replace references to the polyfill.io CDN in our customers’ websites with links to our own, safe, mirror created back in February.

In the meantime, additional threat feed providers have also taken the decision to flag the domain as malicious. We have not outright blocked the domain through any of the mechanisms we have because we are concerned it could cause widespread web outages given how broadly polyfill.io is used with some estimates indicating usage on nearly 4% of all websites.

Corroborating data with Page Shield

The original report indicates that malicious code was injected that, under certain circumstances, would redirect users to betting sites. It was doing this by loading additional JavaScript that would perform the redirect, under a set of additional domains which can be considered Indicators of Compromise (IoCs):

https://www.googie-anaiytics.com/analytics.js
https://www.googie-anaiytics.com/html/checkcachehw.js
https://www.googie-anaiytics.com/gtags.js
https://www.googie-anaiytics.com/keywords/vn-keyword.json
https://www.googie-anaiytics.com/webs-1.0.1.js
https://www.googie-anaiytics.com/analytics.js
https://www.googie-anaiytics.com/webs-1.0.2.js
https://www.googie-anaiytics.com/ga.js
https://www.googie-anaiytics.com/web-1.0.1.js
https://www.googie-anaiytics.com/web.js
https://www.googie-anaiytics.com/collect.js
https://kuurza.com/redirect?from=bitget

(note the intentional misspelling of Google Analytics)

Page Shield, our client side security solution, is available on all paid plans. When turned on, it collects information about JavaScript files loaded by end user browsers accessing your website.

By looking at the database of detected JavaScript files, we immediately found matches with the IoCs provided above starting as far back as 2024-06-08 15:23:51 (first seen timestamp on Page Shield detected JavaScript file). This was a clear indication that malicious activity was active and associated with polyfill.io.

Replacing insecure JavaScript links to polyfill.io

To achieve performant HTML rewriting, we need to make blazing-fast HTML alterations as responses stream through Cloudflare’s network. This has been made possible by leveraging ROFL (Response Overseer for FL). ROFL powers various Cloudflare products that need to alter HTML as it streams, such as Cloudflare Fonts, Email Obfuscation and Rocket Loader

ROFL is developed entirely in Rust. The memory-safety features of Rust are indispensable for ensuring protection against memory leaks while processing a staggering volume of requests, measuring in the millions per second. Rust’s compiled nature allows us to finely optimize our code for specific hardware configurations, delivering performance gains compared to interpreted languages.

The performance of ROFL allows us to rewrite HTML on-the-fly and modify the polyfill.io links quickly, safely, and efficiently. This speed helps us reduce any additional latency added by processing the HTML file.

If the feature is turned on, for any HTTP response with an HTML Content-Type, we parse all JavaScript script tag source attributes. If any are found linking to polyfill.io, we rewrite the src attribute to link to our mirror instead. We map to the correct version of the polyfill service while the query string is left untouched.

The logic will not activate if a Content Security Policy (CSP) header is found in the response. This ensures we don’t replace the link while breaking the CSP policy and therefore potentially breaking the website.

Default on for free customers, optional for everyone else

Cloudflare proxies millions of websites, and a large portion of these sites are on our free plan. Free plan customers tend to have simpler applications while not having the resources to update and react quickly to security concerns. We therefore decided to turn on the feature by default for sites on our free plan, as the likelihood of causing issues is reduced while also helping keep safe a very large portion of applications using polyfill.io.

Paid plan customers, on the other hand, have more complex applications and react quicker to security notices. We are confident that most paid customers using polyfill.io and Cloudflare will appreciate the ability to virtually patch the issue with a single click, while controlling when to do so.

All customers can turn off the feature at any time.

This isn’t the first time we’ve decided a security problem was so widespread and serious that we’d enable protection for all customers regardless of whether they were a paying customer or not. Back in 2014, we enabled Shellshock protection for everyone. In 2021, when the log4j vulnerability was disclosed we rolled out protection for all customers.

Do not use polyfill.io

If you are using Cloudflare, you can remove polyfill.io with a single click on the Cloudflare dashboard by heading over to your zone ⇒ Security ⇒ Settings. If you are a free customer, the rewrite is automatically active. This feature, we hope, will help you quickly patch the issue.

Nonetheless, you should ultimately search your code repositories for instances of polyfill.io and replace them with an alternative provider, such as Cloudflare’s secure mirror under cdnjs (https://cdnjs.cloudflare.com/polyfill/). Website owners who are not using Cloudflare should also perform these steps.

The underlying bundle links you should use are:

For minified: https://cdnjs.cloudflare.com/polyfill/v3/polyfill.min.js
For unminified: https://cdnjs.cloudflare.com/polyfill/v3/polyfill.js

Doing this ensures your website is no longer relying on polyfill.io.

polyfill.io now available on cdnjs: reduce your supply chain risk

Post Syndicated from Sven Sauleau original https://blog.cloudflare.com/polyfill-io-now-available-on-cdnjs-reduce-your-supply-chain-risk


Polyfill.io is a popular JavaScript library that nullifies differences across old browser versions. These differences often take up substantial development time.

It does this by adding support for modern functions (via polyfilling), ultimately letting developers work against a uniform environment simplifying development. The tool is historically loaded by linking to the endpoint provided under the domain polyfill.io.

In the interest of providing developers with additional options to use polyfill, today we are launching an alternative endpoint under cdnjs. You can replace links to polyfill.io “as is” with our new endpoint. You will then rely on the same service and reputation that cdnjs has built over the years for your polyfill needs.

Our interest in creating an alternative endpoint was also sparked by some concerns raised by the community, and main contributors, following the transition of the domain polyfill.io to a new provider (Funnull).

The concerns are that any website embedding a link to the original polyfill.io domain, will now be relying on Funnull to maintain and secure the underlying project to avoid the risk of a supply chain attack. Such an attack would occur if the underlying third party is compromised or alters the code being served to end users in nefarious ways, causing, by consequence, all websites using the tool to be compromised.

Supply chain attacks, in the context of web applications, are a growing concern for security teams, and also led us to build a client side security product to detect and mitigate these attack vectors: Page Shield.

Irrespective of the scenario described above, this is a timely reminder of the complexities and risks tied to modern web applications. As maintainers and contributors of cdnjs, currently used by more than 12% of all sites, this reinforces our commitment to help keep the Internet safe.

polyfill.io on cdnjs

The full polyfill.io implementation has been deployed at the following URL:

https://cdnjs.cloudflare.com/polyfill/

The underlying bundle link is:

For minified: https://cdnjs.cloudflare.com/polyfill/v3/polyfill.min.js
For unminified: https://cdnjs.cloudflare.com/polyfill/v3/polyfill.js

Usage and deployment is intended to be identical to the original polyfill.io site. As a developer, you should be able to simply “replace” the old link with the new cdnjs-hosted link without observing any side effects, besides a possible improvement in performance and reliability.

If you don’t have access to the underlying website code, but your website is behind Cloudflare, replacing the links is even easier, as you can deploy a Cloudflare Worker to update the links for you:

export interface Env {}

export default {
    async fetch(request: Request, env: Env, ctx: ExecutionContext): Promise<Response> {
        ctx.passThroughOnException();

        const response = await fetch(request);

        if ((response.headers.get('content-type') || '').includes('text/html')) {
            const rewriter = new HTMLRewriter()
                .on('link', {
                    element(element) {
                        const rel = element.getAttribute('rel');
                        if (rel === 'preconnect') {
                            const href = new URL(element.getAttribute('href') || '', request.url);

                            if (href.hostname === 'polyfill.io') {
                                href.hostname = 'cdnjs.cloudflare.com';
                                element.setAttribute('href', href.toString());
                            }
                        }
                    },
                })

                .on('script', {
                    element(element) {
                        if (element.hasAttribute('src')) {
                            const src = new URL(element.getAttribute('src') || '', request.url);
                            if (src.hostname === 'polyfill.io') {
                                src.hostname = 'cdnjs.cloudflare.com';
                                src.pathname = '/polyfill' + src.pathname;

                                element.setAttribute('src', src.toString());
                            }
                        }
                    },
                });

            return rewriter.transform(response);
        } else {
            return response;
        }
    },
};

Instructions on how to deploy a worker can be found on our developer documentation.

You can also test the Worker on your website without deploying the worker. You can find instructions on how to do this in another blog post we wrote in the past.

Implemented with Rust on Cloudflare Workers

We were happy to discover that polyfill.io is a Rust project. As you might know, Rust has been a first class citizen on Cloudflare Workers from the start.

The polyfill.io service was hosted on Fastly and used their Rust library. We forked the project to add the compatibility for Cloudflare Workers, and plan to make the fork publicly accessible in the near future.

Worker

The https://cdnjs.cloudflare.com/polyfill/[...].js endpoints are also implemented in a Cloudflare Worker that wraps our Polyfill.io fork. The wrapper uses Cloudflare’s Rust API and looks like the following:

#[event(fetch)]
async fn main(req: Request, env: Env, ctx: Context) -> Result<Response> {
    let metrics = {...};

    let polyfill_store = get_d1(&req, &env)?;
    let polyfill_env = Arc::new(service::Env { polyfill_store, metrics });
    
    // Run the polyfill.io entrypoint
    let res = service::handle_request(req2, polyfill_env).await;

    let status_code = if let Ok(res) = &res {
        res.status_code()
    } else {
        500
    };
    metrics
        .requests
        .with_label_values(&[&status_code.to_string()])
        .inc();

    ctx.wait_until(async move {
        if let Err(err) = metrics.report_metrics().await {
            console_error!("failed to report metrics: {err}");
        }
    });

    res
}

The wrapper only sets up our internal metrics and logging tools, so we can monitor uptime and performance of the underlying logic while calling the Polyfill.io entrypoint.

Storage for the Polyfill files

All the polyfill files are stored in a key-value store powered by Cloudflare D1. This allows us to fetch as many polyfill files as we need with a single SQL query, as opposed to the original implementation doing one KV get() per file.

For performance, we have one Cloudflare D1 instance per region and the SQL queries are routed to the nearest database.

cdnjs for your JavaScript libraries

cdnjs is hosting over 6k JavaScript libraries as of today. We are looking for ways to improve the service and provide new content. We listen to community feedback and welcome suggestions on our community forum, or cdnjs on GitHub.

Page Shield is also available to all paid plans. Log in to turn it on with a single click to increase visibility and security for your third party assets.

Cloudflare’s Handling of an RCE Vulnerability in cdnjs

Post Syndicated from Jonathan Ganz original https://blog.cloudflare.com/cloudflares-handling-of-an-rce-vulnerability-in-cdnjs/

Cloudflare's Handling of an RCE Vulnerability in cdnjs

Cloudflare's Handling of an RCE Vulnerability in cdnjs

cdnjs provides JavaScript, CSS, images, and fonts assets for websites to reference with more than 4,000 libraries available. By utilizing cdnjs, websites can load faster with less strain on one’s own origin server as files are served directly from Cloudflare’s edge. Recently, a blog post detailed a vulnerability in the way cdnjs’ backend automatically keeps the libraries up to date.

This vulnerability allowed the researcher to execute arbitrary code, granting the ability to modify assets. This blog post details how Cloudflare responded to this report, including the steps we took to block exploitation, investigate potential abuse, and remediate the vulnerability.

This vulnerability is not related to Cloudflare CDN. The cdnjs project is a platform that leverages Cloudflare’s services, but the vulnerability described below relates to cdnjs’ platform only. To be clear, no existing libraries were modified using this exploit. The researcher published a new package which demonstrated the vulnerability and our investigation concluded that the integrity of all assets hosted on cdnjs remained intact.

Disclosure Timeline

As outlined in RyotaK’s blog post, the incident began on 2021-04-06. At around 1100 GMT, RyotaK published a package to npm exploiting the vulnerability. At 1129 GMT, cdnjs processed this package, resulting in a leak of credentials. This triggered GitHub alerting which notified Cloudflare of the exposed secrets.

Cloudflare disabled the auto-update service and revoked all credentials within an hour. In the meantime, our security team received RyotaK’s remote code execution report through HackerOne. A new version of the auto-update tool which prevents exploitation of the vulnerability RyotaK reported was released within 24 hours.

Having taken action immediately to prevent exploitation, we then proceeded to redesign the auto-update pipeline. Work to completely redesign it was completed on 2021-06-03.

Blocking Exploitation

Before RyotaK reported the vulnerability via HackerOne, Cloudflare had already taken action. When GitHub notified us that credentials were leaked, one of our engineers took immediate action and revoked them all. Additionally, the GitHub token associated with this service was automatically revoked by GitHub.

The second step was to bring the vulnerable service offline to prevent further abuse while we investigated the incident. This prevented exploitation but also made it impossible for legitimate developers to publish updates to their libraries. We wanted to release a fixed version of the pipeline used for retrieving and hosting new library versions so that developers could continue to benefit from caching. However, we understood that a stopgap was not a long term fix, and we decided to review the entire current solution to identify a better design that would improve the overall security of cdnjs.

Investigation

Any sort of investigation requires access to logs and all components of our pipeline generate extensive logs that prove valuable for forensics efforts. Logs produced by the auto-update process are collected in a GitHub repository and sent to our logging pipeline. We also collect and retain logs from cdnjs’ Cloudflare account. Our security team began reviewing this information as soon as we received RyotaK’s initial report. Based on access logs, API token usage, and file modification metadata, we are confident that only RyotaK exploited this vulnerability during his research and only on test files. To rule out abuse, we reviewed the list of source IP addresses that accessed the Workers KV token prior to revoking it and only found one, which belongs to the cdnjs auto-update bot.

The cdnjs team also reviewed files that were pushed to the cdnjs/cdnjs GitHub repository around that time and found no evidence of any other abuse across cdnjs.

Remediating the Vulnerability

Around half of the libraries on cdnjs use npm to auto-update. The primary vector in this attack was the ability to craft a .tar.gz archive with a symbolic link and publish it to the npm registry. When our pipeline extracted the content it would follow symlinks and overwrite local files using the pipeline user privileges. There are two fundamental issues at play here: an attacker can perform path traversal on the host processing untrusted files, and the process handling the compressed file is overly privileged.

We addressed the path traversal issue by checking that the destination of each file in the tarball will be contained within the target directory that the update process has designated for that package. If the file’s full canonical path doesn’t begin with the destination directory’s full path, we log this as a warning and skip extracting that file. This works fairly well, but as noted in the comment above this check, if the compressed file uses UTF-8 encoding for filenames, this check may not properly canonicalize the path. If this canonicalization does not occur, the path may contain path traversal, even though it starts with the correct destination path.

To ensure that other vulnerabilities in cdnjs’ publication pipeline cannot be exploited, we configured an AppArmor profile for it. This limits the capabilities of the service, so even if an attacker successfully instructed the process to perform an action, the operating system (kernel / security feature) will not allow any action outside of what it is allowed to do.

For illustration, here’s an example:

/path/to/bin {
  network,
  signal,
  /path/to/child ix,
  /tmp/ r,
  /tmp/cache** rw,
  ...
}

In this example, we only allow the binary (/path/to/bin) to:

  • access all networking
  • use all signals
  • execute /path/to/child (which will inherit the AppArmor profile)
  • read from /tmp
  • read+write under /tmp/cache.

Any attempt to access anything else will be denied. You can find the complete list of capabilities and more information on AppArmor’s manual page.

In the case of cdnjs’ autoupdate tool, we limit execution of applications to a very specific set, and we limit where files can be written.

Fixing the path traversal and implementing the AppArmor profile prevents similar issues from being exploited. However, having a single layer of defense wasn’t enough. We decided to completely redesign the auto-update process entirely to isolate each step, as well as each library it processes, thus preventing this entire class of attacks.

Redesigning the system

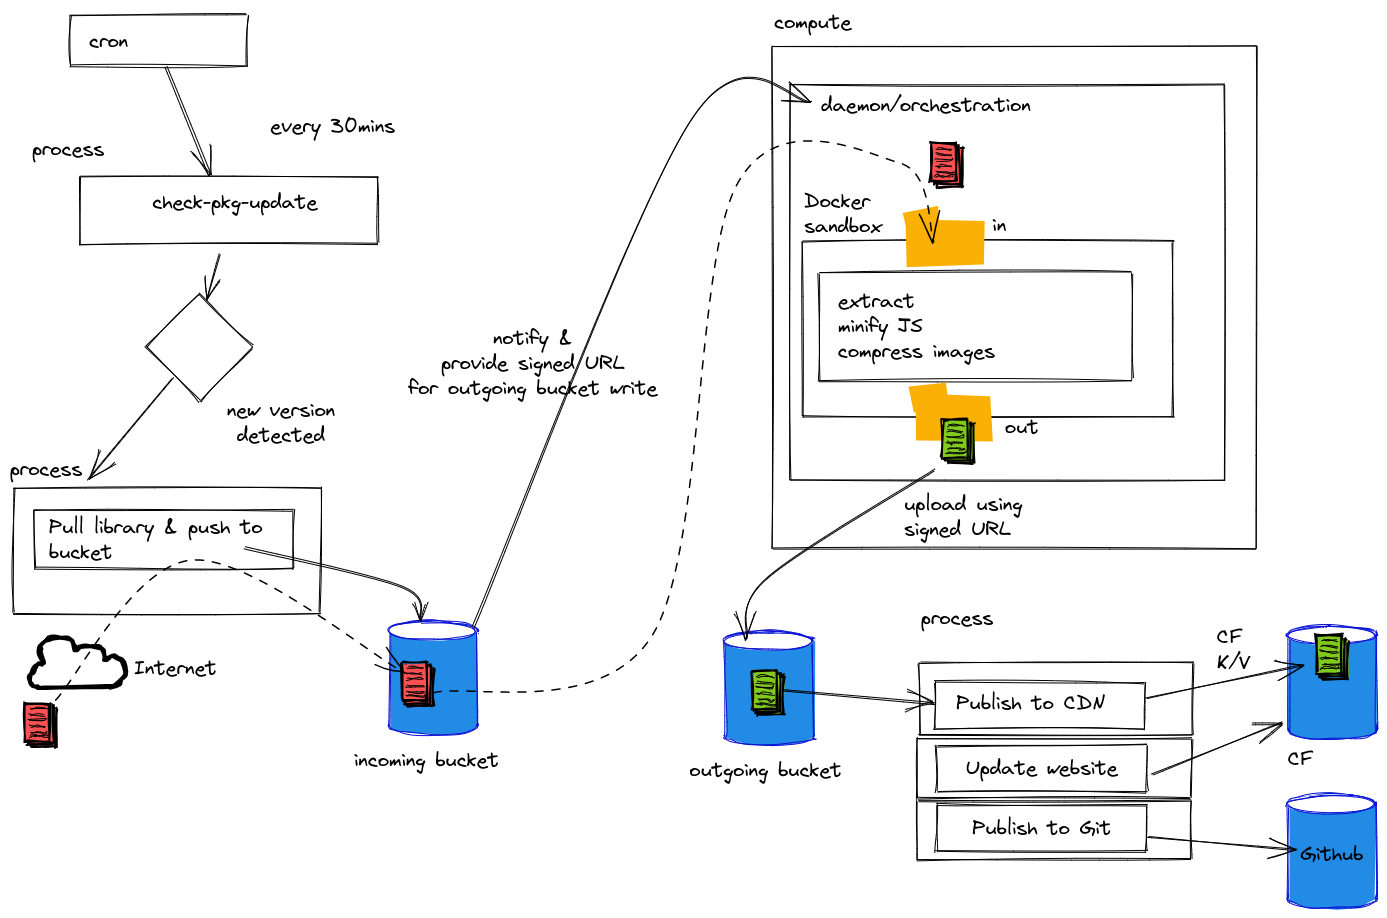
The main idea behind the redesign of the pipeline was to move away from the monolithic auto-update process. Instead, various operations are done using microservices or daemons which have well-defined scopes. Here’s an overview of the steps:

Cloudflare's Handling of an RCE Vulnerability in cdnjs

First, to detect new library versions, two daemons (for both npm and git based updates) are regularly running. Once a new version has been detected, the files will be downloaded as an archive and placed into the incoming storage bucket.

Writing a new version in the incoming bucket triggers a function that adds all the information we need to update the library. The function also generates a signed URL allowing for writing in the outgoing bucket, but only in a specific folder for a given library, reducing the blast radius. Finally, a message is placed into a queue to indicate that the new version of the given library is ready to be published.

A daemon listens for incoming messages and spawns an unprivileged Docker container to handle dangerous operations (archive extraction, minifications, and compression). After the sandbox exits, the daemon will use the signed URL to store the processed files in the outgoing storage bucket.

Finally, multiple daemons are triggered when the finalized package is written to the outgoing bucket. These daemons publish the assets to cdnjs.cloudflare.com and to the main cdnjs repository. The daemons also publish the version specific URL, cryptographic hash, and other information to Workers KV, cdnjs.com, and the API.

In this revised design, exploiting a similar vulnerability would happen in the sandbox (Docker container) context. The attacker would have access to container files, but nothing else. The container is minimal, ephemeral, has no secrets included, and is dedicated to a single library update, so it cannot affect other libraries’ files.

Our Commitment to Security

Beyond maintaining a vulnerability disclosure program, we regularly perform internal security reviews and hire third-party firms to audit the software we develop. But it is through our vulnerability disclosure program that we receive some of the most interesting and creative reports. Each report has helped us improve the security of our services. In this case, we worked with RyotaK to not only address the vulnerability, but to also ensure that their blog post was detailed and accurate. We invite those that find a security issue in any of Cloudflare’s services to report it to us through HackerOne.

Migrating cdnjs to serverless with Workers KV

Post Syndicated from Tyler Caslin original https://blog.cloudflare.com/migrating-cdnjs-to-serverless-with-workers-kv/

Migrating cdnjs to serverless with Workers KV

Cloudflare powers cdnjs, an open-source project that accelerates websites by delivering popular JavaScript libraries and resources via Cloudflare’s network. Since our major update in December, we focused on remodelling cdnjs for scalability and resilience. Today, we are excited to announce how Cloudflare delivers cdnjs—a migration to a serverless infrastructure using Cloudflare Workers and its distributed key-value store Workers KV!

What is cdnjs and why do I care?

Migrating cdnjs to serverless with Workers KV

For those unfamiliar, cdnjs is an acronym describing a Content Delivery Network (CDN) for JavaScript (JS). A CDN simply refers to a geographically distributed network of servers that provide Internet content, whether it is memes, cat videos, or HTML pages. In our case, the CDN refers to Cloudflare’s ever expanding network of over 200 globally distributed data centers.

And here’s why this is relevant to you: it makes page load times lightning-fast. Virtually every website you visit needs to fetch JS libraries in order to load, including this one. Let’s say you visit a Sydney-based website that contains a local file from jQuery, a popular library found in 76.2% of websites. If you are located in New York, you may notice a delay, as it can easily exceed 300ms to fetch the file—not to mention the time it takes for the round trips involved with the TLS handshake. However, if the website references jQuery using cdnjs.cloudflare.com, you can retrieve the file from the closest Cloudflare data center in Buffalo, reducing the latency to a blazing 20ms.

While cdnjs operates behind the scenes, it is used by over 11% of websites, making the Internet a much faster and more reliable place. In July, cdnjs served almost 190 billion requests—an enormous 3.46PB of data.

Where are the files stored?

Migrating cdnjs to serverless with Workers KV

While cdnjs speeds up the Internet, it certainly isn’t magic!

Historically, a number of load-balanced machines at one of Cloudflare’s core data centers would periodically pull cdnjs files from a backing store, acting as the origin for cdnjs.cloudflare.com. When a new file is requested, it is cached by Cloudflare, allowing it to be fetched quickly from any of our data centers.

The backing store is a catalogue of JS, CSS, and other web libraries in the form of an open-source GitHub repository. What this means is that anyone—including you—can contribute to it, subject to review and other processes.

However, until recently, these existing operations were very labor intensive and fragile.

This blog post will explain why we changed the infrastructure behind cdnjs to make it faster, more reliable, and easier to maintain. First, we will discuss how the community used to contribute to cdnjs, outlining the pains and concerns of the old system. Then, we will explore the benefits of migrating to Workers KV. After, we will dive into the new architecture, as well as upgrades to the website and cdnjs API. Finally, we will review the history of cdnjs, and where it is headed in the future.

If you think you know how to make a PR, think again

Migrating cdnjs to serverless with Workers KV

For the non-technical reader, a pull request (PR) is a request to merge changes you’ve made to a repository. Traditionally, if you wanted to include your JavaScript library in cdnjs, you would first create a PR on GitHub to cdnjs/cdnjs with a JSON file describing your package and additional files for any version you wished to include. Once your PR was approved by our old bot, manually reviewed, and then merged by a maintainer, your package would be integrated with cdnjs.

Sounds easy, right? You can just fork the repo, clone it, and copy paste a few files, no?

Exactly. Contributing was easy if you had several hours to burn, a case-sensitive file system, and a couple hundred gigabytes of free disk space to git clone the 300GB repo. If you were short on time—no problem, you could always use your advanced knowledge of git sparse-checkout to get the job done. Don’t know git? Just add one file at a time manually through GitHub’s UI.

I think you get the point. I know I certainly did when I naively spent 10 hours cloning the repo, only to discover that macOS is case-insensitive by default.

However, updating cdnjs was not only difficult for the contributors, but also the maintainers. Historically, the community was able to contribute version files directly, which could potentially be malicious. This created lots of work for maintainers, requiring them to inspect each file manually, diffing files against the official library source and running malware checks.
So how did packages update once they were in cdnjs? In the JSON file describing each package, there was an optional auto-update definition telling the bot where to look for new versions of the library. If present, when your package released a new version from npm or GitHub, the bot would download it, pushing the files to cdnjs/cdnjs and computed Subresource Integrity (SRI) hashes to cdnjs/SRIs. If the auto-update property was missing, it would be your responsibility to make manual PRs to update cdnjs with any future versions.

A wake-up call for cdnjs

Migrating cdnjs to serverless with Workers KV

In April, during maintenance at one of our core data centers, a technician accidentally disconnected the cables supplying all external connections to our other data centers, causing the data center to go offline for approximately four hours. This incident served as the first wake-up call for cdnjs, especially since the affected data center housed the primary cdnjs origin web servers. In this case, we did have a backup running on an external provider, but what really saved us was Cloudflare’s global cache, which minimized the impact of the outage as only uncached assets failed to load.

We started to think about how we can improve both the reliability and performance of how we serve cdnjs. We went straight to Cloudflare Workers, our own platform for developing on the edge. One powerful tool built into Workers is Workers KV—a low-latency, globally distributed key-value store optimized for high-read applications.

We put two and two together, realizing that instead of pulling the cdnjs/cdnjs repository and serving files from disk, we could cut the physical machines out entirely, distributing the data around the world and serving files straight from the edge. That way, cdnjs would be able to recover from any origin data center failure, while also increasing its scalability.

Workers KV to the rescue

Migrating cdnjs to serverless with Workers KV

At first glance, the decision to use Workers KV was a no-brainer. Since files in cdnjs never change but require frequent reads, Workers KV was a perfect fit.

However, as we planned our migration, we became concerned that with over 7 million assets in cdnjs, there would undoubtedly exist files that exceed Workers KV’s 10MiB value limit. After investigating, we discovered that several hundred cdnjs files were oversized, the majority being JavaScript Source Maps.

Then the idea hit us. We could store compressed versions of cdnjs files in Workers KV, not only solving our oversized file issue, but also optimizing how we serve files.

If you pay the Internet bill, you’ll know that bandwidth is expensive! For this reason, all modern browsers will try to fetch compressed web content whenever it is available. Similarly, within Cloudflare we often experiment with on-the-fly compression to reduce our bandwidth, always serving compressed content to the eyeball when it is accepted. As a result, we decided to compress all cdnjs files ahead of time, writing them to Workers KV with both optimal Brotli and gzip forms. That way, we could increase the compression level compared to on-the-fly compression as we no longer have the latency requirements.

This means we now serve cdnjs files faster and smaller!

A complete makeover for cdnjs

Migrating cdnjs to serverless with Workers KV

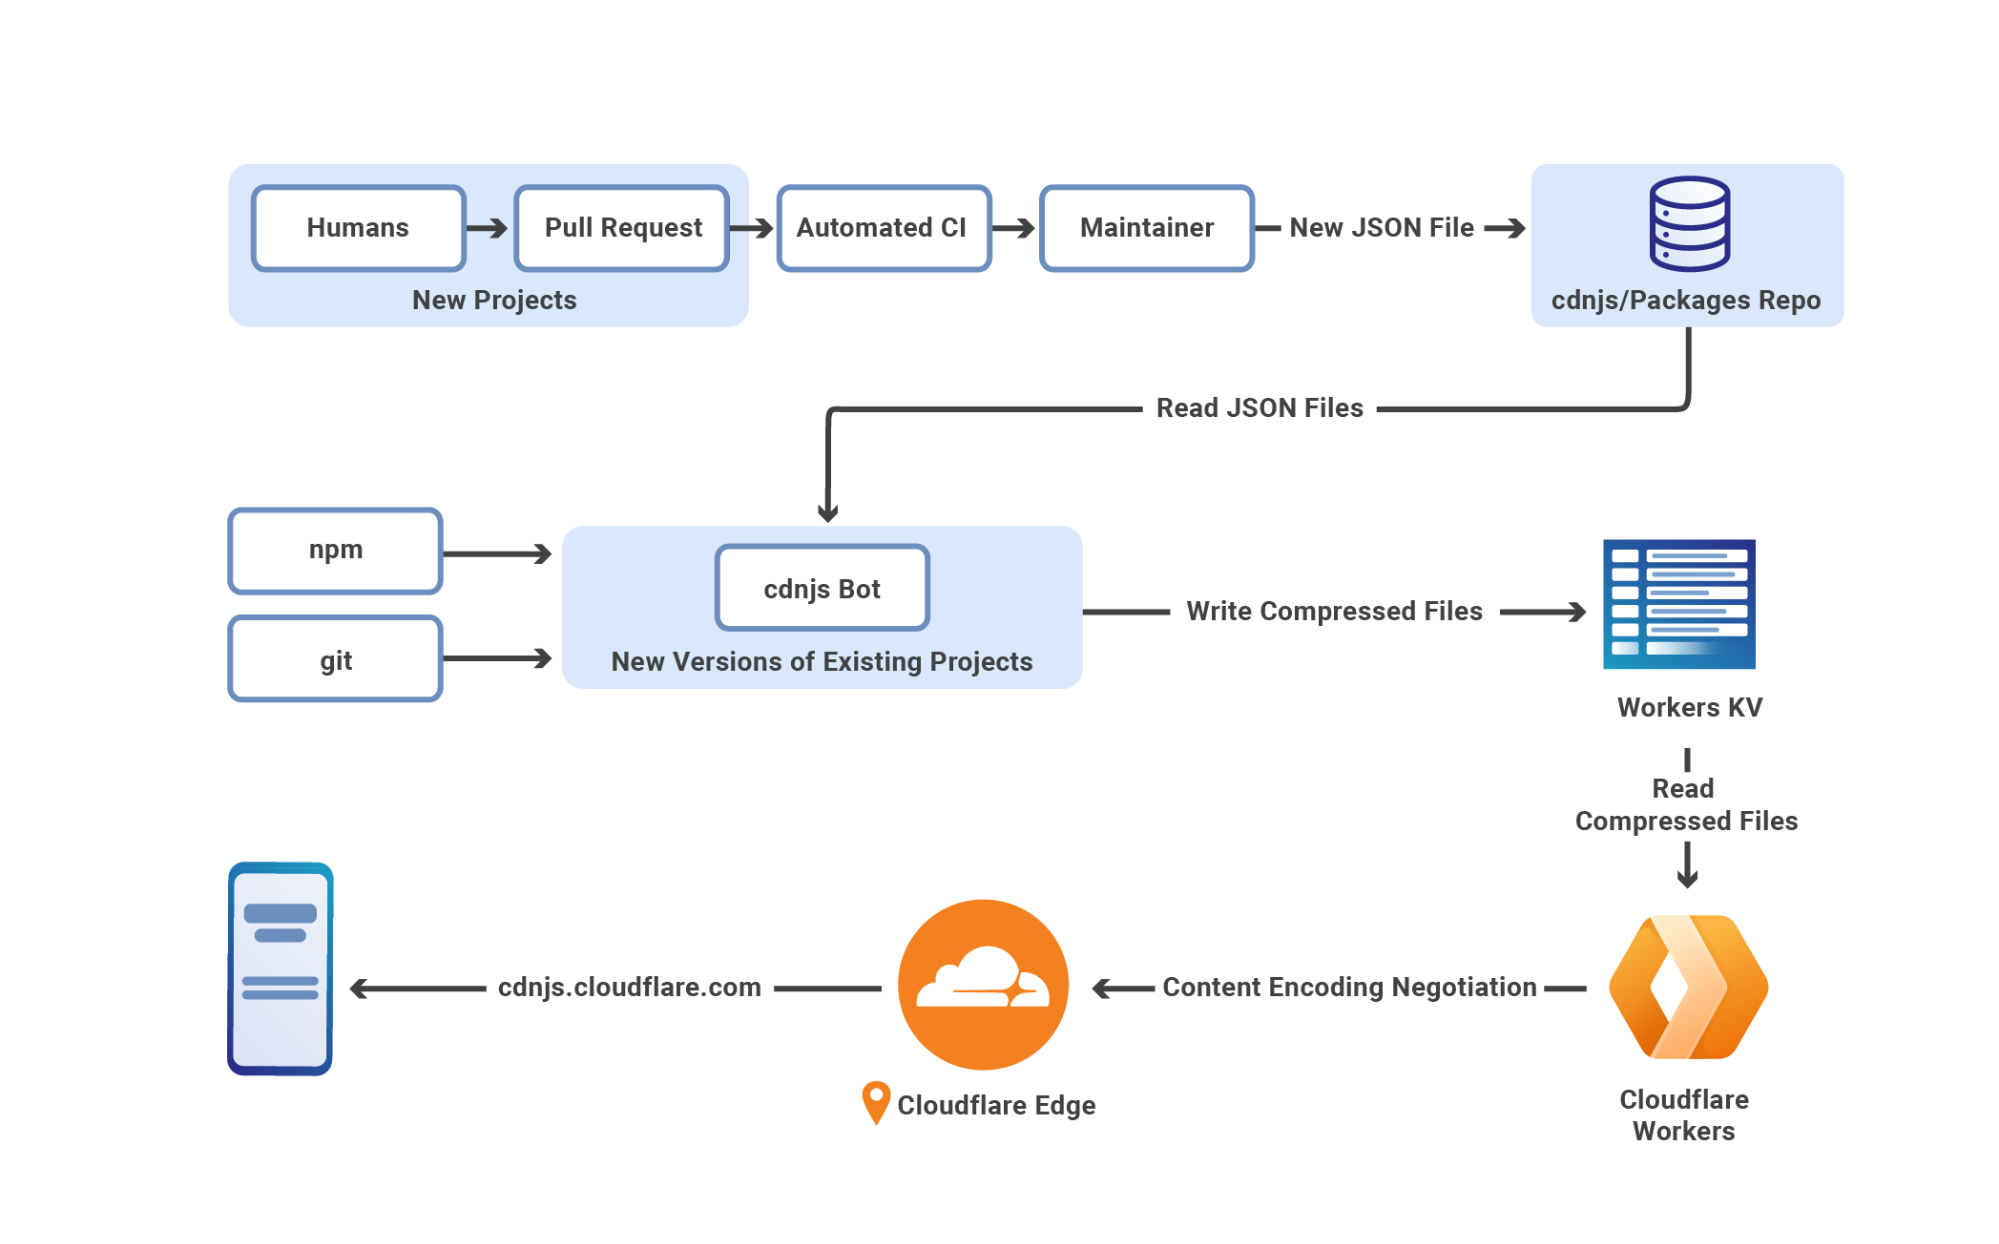
Today, if you want to include your JavaScript library in cdnjs, you first create a PR on GitHub to our new repository cdnjs/packages. The repo is easily cloneable at 50MB and consists of thousands of JSON files, each describing a cdnjs package and how it is auto-updated from npm or git. Once your file is validated by our automated CI—powered by a new bot—and merged by a maintainer, your package would be automatically enrolled in our auto-update service.

In the new system, security and maintainability are prioritized. For starters, cdnjs version files are created by our bot, minimizing the possibility of human error when merging a new version. While the JSON files in cdnjs/packages are added by error-prone humans, they are inspected by our bot before being approved by a maintainer. Each file is automatically validated against a JSON schema, as well as checked for popularity on npm or GitHub.

When the bot discovers a new release, it pushes Brotli and gzip-compressed versions of the files to a files namespace in Workers KV. With each entry, the bot writes some metadata in Workers KV for the ETag and Last-Modified HTTP headers. Similar to before, the bot also computes Subresource Integrity (SRI) hashes of the uncompressed files, but now pushes them instead to a SRIs namespace in Workers KV.

Then, when a new file is requested from cdnjs.cloudflare.com, a Cloudflare Worker will inspect the client’s Accept-Encoding header, fetching either the Brotli or gzip-compressed version with its ETag and Last-Modified metadata from Workers KV. As the compressed file travels back through Cloudflare, it is cached for future requests and uncompressed on-the-fly if needed.

At the moment, there are still a handful of files exceeding Workers KV’s size limit. Consequently, if the Cloudflare Worker fails to retrieve a file from Workers KV, it is fetched from the origin backed by the original git repo. In the coming months, we plan on gradually removing this infrastructure.

Scaling the website and API

Migrating cdnjs to serverless with Workers KV

Besides the core cdnjs infrastructure, many of its other components received upgrades as well!

On the cdnjs project’s homepage, you will be greeted by a slick new beta website built by Matt. Constructed with Vue and Nuxt, the beta website is powered entirely by the cdnjs API. As a result, it is always up-to-date with the latest package information and requires low resource usage to serve the site—which runs completely on the client-side after the first page load—helping us scale with cdnjs’s never-ending growth.

In fact, the cdnjs API also strengthened its scalability, benefitting from a serverless architecture close to the one we have seen with cdnjs and Workers KV.

Before migrating to Workers KV, the cdnjs API relied on a regularly scheduled process that involved generating about 300MB of metadata. The cdnjs API’s backend would then fetch this enormous “package.min.js” file into memory and use it to operate the API. If you are curious, the file is still being hosted here, but be warned—it may lag your browser! Similarly, file SRIs were pushed to cdnjs/SRIs, which was cloned by the API locally to serve SRI responses.

After all cdnjs files (within the permitted size limit) were moved to Workers KV, these legacy processes became unsustainable, requiring millions of reads and an unreasonable amount of time. Therefore, we decided to upload all metadata found into Workers KV. We split the metadata into four namespaces—one for package-level metadata, one for version-specific metadata, one containing aggregated metadata, and one for file SRIs.

Similar to cdnjs’s serverless design, a Cloudflare Worker sits on top of metadata.speedcdnjs.com, serving data from Workers KV using several public endpoints. Currently, the cdnjs API is fully integrated with these endpoints, which provide an elegant solution as cdnjs continues to scale.

Transparency and the future of cdnjs

Since its birth in January 2011, cdnjs has always been deeply rooted in transparency, deriving its strength from the community. Even when cdnjs exploded in size and its founders Ryan Kirkman and Thomas Davis teamed up with us in June 2011, the project remained entirely open-source on GitHub.

As the years passed, it became harder for the founders to stay active, heavily depending on the community for support. With a nearly nonexistent budget and little access to the repository, core cdnjs maintainers were challenged every day to keep the project alive.

Last year, this led us to contact the founders, who were happy to have our assistance with the project. With Cloudflare’s increased role, cdnjs is as stable as ever, with active members from both Cloudflare and the community.

However, as we remove our reliance on the legacy system and store files in Workers KV, there are concerns that cdnjs will become proprietary. Don’t worry, we are working hard to ensure that cdnjs remains as transparent and open-source as possible. To help the community audit updates to Workers KV, there is a new repository, cdnjs/logs, which is used by the bot to log all Workers KV-related events. Furthermore, anyone can validate the integrity of cdnjs files by fetching SRIs from the cdnjs API.

Conclusion

Overall, this past year has been a turbulent time for cdnjs, but all of its shortcomings have acted as red flags to help us build a better system. Most recently, we have mitigated the risks of depending on physical machines at a single location, migrating cdnjs to a serverless infrastructure where its files are stored in Workers KV.

Today, cdnjs is in good hands, and is not going away anytime soon. Shout out especially to the maintainers Sven and Matt for creating tons of momentum with the project, working on everything from scaling cdnjs to editing this post.

Moving forward, we are committed to making cdnjs as transparent as possible. As we continue to improve cdnjs, we will release more blog posts to keep the community up to date. If you are interested, please subscribe to our blog. After all, it is the community that makes cdnjs possible! A special thanks to our active GitHub contributors and members of the cdnjs Community Forum for sticking with us!