Tag Archives: data-movement

The Evolution of Cassandra Data Movement at Netflix

Post Syndicated from Netflix Technology Blog original https://medium.com/netflix-techblog/the-evolution-of-cassandra-data-movement-at-netflix-6e13329c80a1

By Guil Pires, Jennifer Prince, Jose Camacho, Ken Kurzweil, Phanindra Chunduru

Background

In a previous post, we introduced Data Bridge, a unified management plane for batch Data Movement at Netflix. Historically, several bespoke Data Movement connectors were developed across different engineering organizations to fulfill their specific requirements. Over the last few years, the Data Movement team has started centralizing these offerings through an abstraction that provides a catalog of connectors, along with simple UI and APIs to initiate Data Movement jobs.

One such case is the Cassandra to Iceberg connector. Apache Cassandra powers mission critical applications at Netflix, including Member, Billing, Recommendations, Subscriptions and many more. These use cases heavily leverage Data Movement to Apache Iceberg for many analytics and operational tasks, and central to this movement was a connector for Cassandra to Iceberg built in-house named Casspactor. As many Cassandra based Data Abstractions emerged, such as Key Value, Time Series and Graph — the need for larger and more complex Data Movement with transformations became more critical to the business.

Data movements are fundamentally fulfilled by leveraging the existing Cassandra backup infrastructure. Regularly scheduled backups are performed directly on the Apache Cassandra nodes, via a sidecar process managing the upload of all necessary SSTables and associated Metadata files directly into Amazon S3. When a Data Movement job is initiated, the job constructs the specific backup structure it needs by referencing the S3 based metadata, allowing it to precisely locate the SSTable files. The engine then downloads these files, performs the required mutation compaction and processing, and finally writes the fully transformed, compacted data directly into the target Apache Iceberg tables.
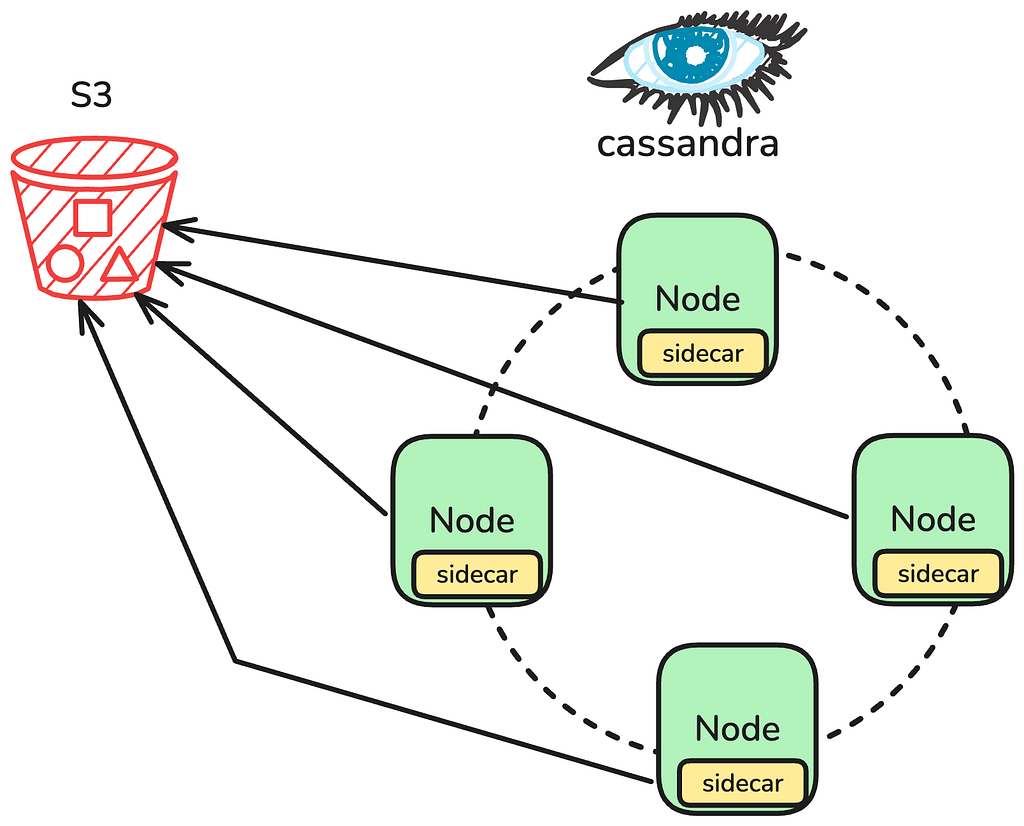
Image 1: Cassandra Cluster Backups to S3

Casspactor: The Engine We Outgrew

Casspactor processed roughly 1,200 data movements per day, transferring approximately 3 PB of data from Apache Cassandra into Apache Iceberg tables. It served some of the most critical workloads at Netflix. For years, it worked. Then, two compounding challenges made it clear we needed a fundamentally different architecture.

Fragile Metadata Dependencies

Before Casspactor could move a single record, it needed to answer a deceptively simple question: which backup exists, is it complete, and what does it contain?

Casspactor assembled this answer from multiple independent systems:
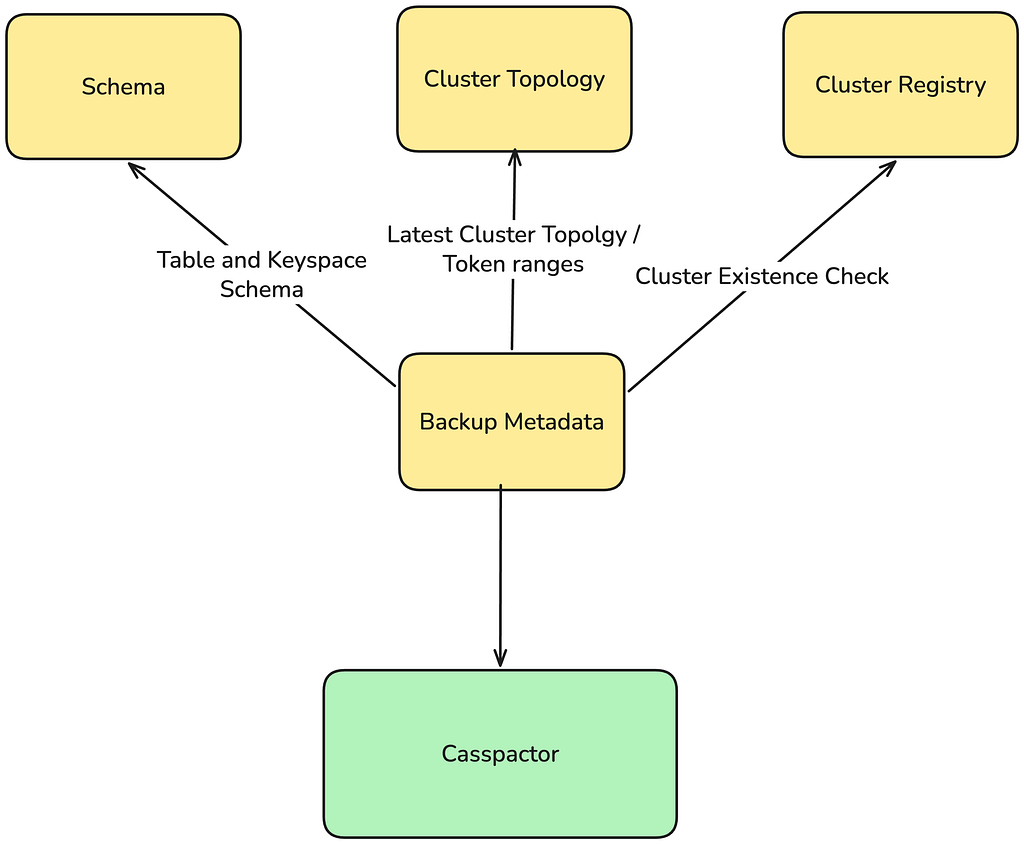
Image 2: Casspactor’s Composite View of a Backup

Each system had its own failure modes, update cadences, and accuracy guarantees. Casspactor’s view of the world was a composite, and composites diverge from reality.

Metadata fell out of sync with actual backups, causing Casspactor to read stale or incorrect data silently. Routine maintenance on the Cassandra Clusters triggered uncoordinated snapshots, and because Casspactor required all nodes in a region to snapshot at the same clock second, a single node replacement could break data movement for an entire region.

The fix was hiding in plain sight. The answer to “which backup exists and is it complete?” already lived in the backup storage layer (Amazon S3) itself. By reading metadata directly from the backup files, we could replace the entire dependency chain with a single source of truth.

Every Connector Inherited Casspactor’s Limitations

Cassandra at Netflix does not just store raw tables. It backs higher level data abstractions, such as Key Value, Time Series, and others, each with its own data model, access patterns, and semantics. When any of these abstractions needed to move data to Iceberg, they all funneled through Casspactor.

Every abstraction inherited Casspactor’s constraints:

  • Skewed partition failures: Casspactor could not handle tables with large partitions, a common pattern in Key Value and Time Series workloads. Jobs crashed with out-of-memory errors on some of Netflix’s largest datasets.
  • No data model awareness: Casspactor moved raw Cassandra tables as is. Connectors for Key Value and other abstractions had to bolt on post processing to reconstruct their data models from the raw output — extra cost, extra complexity, and an extra surface for failures.
  • Intermediate table bloat: Casspactor wrote to an intermediate Iceberg table before producing the final output. The Key Value connector added another intermediate table and a snapshots table. Connectors for abstractions on top of Key Value added even more. This compounded into significant storage cost overhead.
  • Inability to Time Travel: by relying on multiple services to compose a backup unit, Casspactor was unable to restore prior backups in the event of cluster Topology or Keyspace schema changes.
  • Monolithic design: Casspactor was built as a single connector, not as an engine. There was no way to build a family of purpose built connectors on a shared foundation.

We needed something fundamentally different: an engine that reads directly from backups in S3, produces standard Spark DataFrames, and lets each data abstraction build its own connector with full awareness of its data model. One foundation, many connectors.

The New Stack: A Layered Architecture

The new architecture, built upon the foundation of Apache Cassandra Analytics and the in-house Move Data framework, represents a fundamental shift toward a layered, purpose-built stack designed for reuse and maintainability. This new engine was conceived with clear separation of concerns, moving away from Casspactor’s monolithic design. The architecture is intentionally layered with the foundation being a core S3 reading capability: the Cassandra Analytics Wrapper, which is built on top of the Open Source Cassandra Analytics with Netflix’s internal backup representation and an S3 Client.

This layer handles the raw data retrieval from backups, translating it into standard Spark DataFrames. Sitting atop this foundation is a “Connector Factory” model, via both Java UDFs and transforms which allows individual data abstractions (Key Value, Time Series, others) to build highly optimized, data model aware connectors that process the generic Spark DataFrames, avoiding the need for complex, expensive, and failure-prone post-processing steps. This layered approach ensures that improvements to the core reading engine benefit all connectors, while the connectors themselves are focused solely on data transformation.
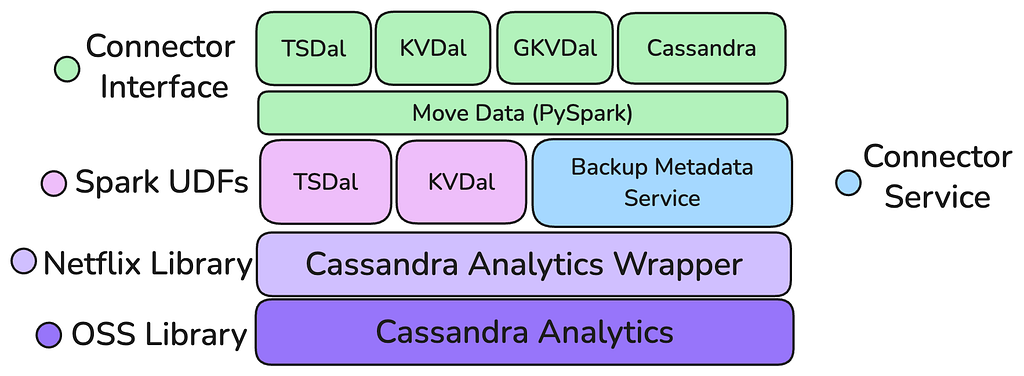
Image 3: The new Connector layered stack
  • Handles Skewed Partitions: By moving the mutation compaction and processing to the Executor level within Spark, the new engine can efficiently handle tables with highly skewed or wide partitions, a major pain point for Casspactor. Crucially, this processing occurs without excessive data shuffling, preventing out-of-memory errors and enabling reliable movement of Netflix’s largest datasets.
  • Operates at Spark DataFrames (No Intermediary Tables): The new architecture directly generates standard Spark DataFrames from the Cassandra backups. This eliminates the need for Casspactor’s costly, multi-stage intermediate Iceberg tables, which led to storage bloat and operational complexity. This native DataFrame operation enables the “Connector Factory” by providing a universal, easily consumable interface for building diverse, model specific connectors.
  • Jobs Auto Size: The engine integrates intelligent auto-sizing capabilities, allowing jobs to dynamically adjust resource consumption based on the source table’s characteristics. This removes the burden of manual tuning from engineering teams, ensuring optimal performance and cost efficiency without sacrificing reliability.
  • Reduced Dependencies: By reading metadata directly from the backup files stored in S3, the new stack removes the fragile, multi-service dependency chain that plagued Casspactor. S3 becomes the single, authoritative source of truth for backup existence and completeness, vastly improving data movement reliability and consistency.
  • Time Travel: A critical feature of the new stack is the ability to process the schema, cluster topology, and data as a cohesive unit at a specific point in time. This capability provides robust time travel functionality, essential for auditing, debugging, disaster recovery and reproducing past data states.
  • Performance: Collectively, these architectural improvements, including native DataFrame processing, optimized partition handling, and streamlined metadata retrieval have resulted in notable performance gains, reducing overall data movement execution runtime and cost compared to the legacy Casspactor system.
  • Cost: by eliminating intermediary Iceberg tables and efficient SSTable compaction on Executors, the new stack needs a significantly smaller storage and compute footprint leading to significant cost savings in the order of USD millions.

The Journey Towards a Safe Migration

The successful validation of the new stack was the critical first step, but it only marked the beginning of the most challenging phase: the migration. Large scale data migrations are inherently complex, high-risk undertakings that can be time consuming and often result in customer frustration and service disruption. To navigate the high stakes of decommissioning a mission-critical system like Casspactor and seamlessly replacing it, we needed a strategy that prioritized reliability and transparency above all else.

The migration was fundamentally enabled by a Like-for-Like strategy, which served as the cornerstone of our Platform Engineering philosophy, abstracting complexity. The core tenet was to maintain absolute consistency across the user-facing interface, the output contract, and the final data artifact. This meant ensuring that the data movement parameters defined via the Data Bridge abstraction remained unchanged, and, critically, the schema, metadata, and data within the destination Iceberg tables were identical to the legacy output. By preserving these external contracts, we eliminated the need for complex, time-consuming coordination with dozens of internal teams who relied on these data pipelines. This approach transformed the migration from a distributed, high-risk, multi-team effort into an internal platform implementation detail, allowing us to achieve a transparent, zero-impact transition and accelerate the retirement of the legacy system without requiring any code changes or validation from downstream users.

To navigate this migration, we developed a strategy anchored by three core pillars that serve as a blueprint for successful, large-scale data migrations:

  1. Validation: Establishing and maintaining absolute confidence in data consistency through rigorous, ongoing validation.
  2. Visibility: Instrumenting every part of the system to provide a clear, real-time understanding of migration progress and system health.
  3. Safety: Ensuring user impact is minimized or eliminated, despite the inevitable system failures, by leveraging abstractions and robust fallbacks.

The next section will provide a detailed exploration of these key pillars.

Pillar 1: Validation

Trust is earned, and in data migration, it is earned one row at a time. The first pillar is the most critical: providing a measurable guarantee to users and partners that the data produced by the new system is an exact, row-by-row replica of the data produced by the old one.

Our foundational tactic was deploying the new Move Data connector in a “shadow” testing that ran in parallel with the production Casspactor jobs. This allowed us to validate the new system with real-world, production workloads without any customer impact.
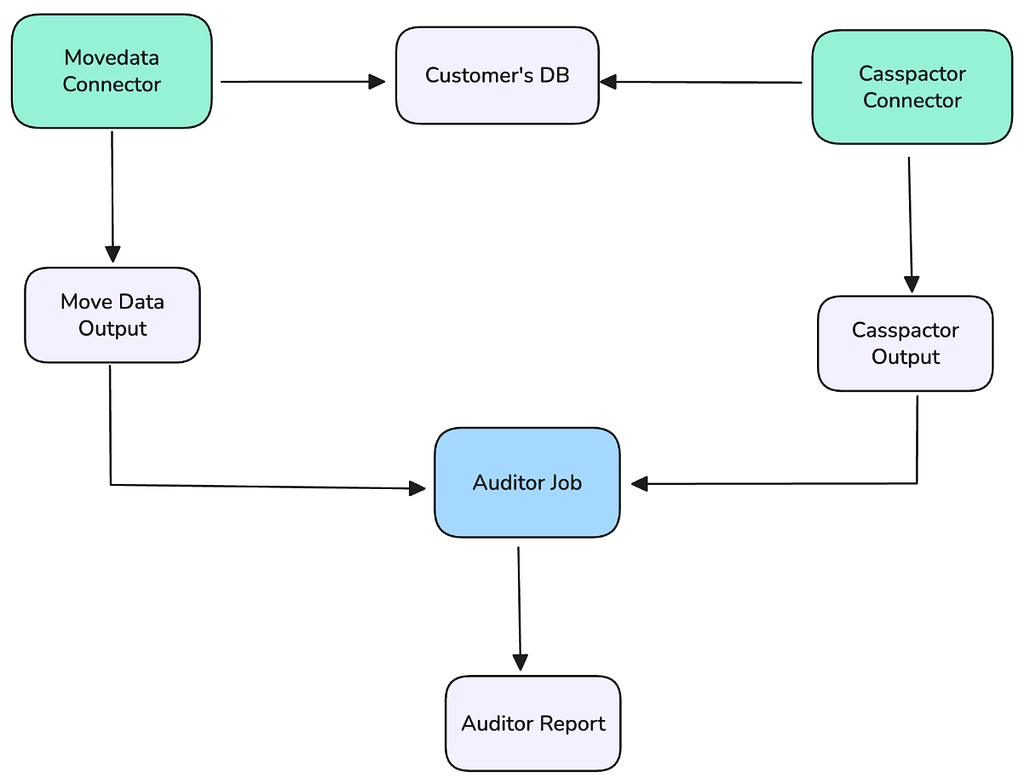
Image 4: Shadow job structure leveraged for data validation
  • Let C be the set of rows in the legacy Casspactor output (Iceberg table).
  • Let M be the set of rows in the new Move Data output (Iceberg table).

The test for trust: prove that C = M. This required continuously checking for two conditions:

  1. Rows in C but not in M (C-M): The new system missed data.
  2. Rows in M but not in C (M-C): The new system introduced phantom or erroneous data.

Any result where the cardinality of these difference sets (the number of differing rows) was greater than zero triggered an immediate, high-priority investigation. The target was 100% similarity.

Uncovering and Resolving Disparities

The shadow mode quickly became a powerful forensic tool, exposing “unknown unknowns”, subtle discrepancies that were not bugs in the new system but rather differences in behavior between the new and old systems. Resolving these was the core work of building trust. For each problem we initiated an investigation log where we captured the details, logs, queries that allowed us to diagnose. Based on the assessment the issues were categorized so that similar differences on other datasets were later resolved affecting many of the shadow pipelines.

Maintaining an investigation log was critical to organize the outstanding issues and effectively communicate to stakeholders the progress and confidence of the new connector so that we effectively measure the appropriate level of “confidence” to initiate the migration.

We observed differences in how connectors leverage reference timestamps for Time-to-Live, Consistency Levels, backup selection, and various internal business logic. This continuous, data-driven cycle of discovery and resolution was the mechanism by which we built confidence in the new architecture.

Pillar 2: Visibility

Trust is built in the background, but an active migration requires real-time insight: Visibility. The second pillar involves instrumenting the system to provide an unambiguous, clear understanding of operational health and migration progress.

We extended our instrumentation to the overall migration workflow and its dependencies:

  • Dashboards: We created centralized dashboards to track migration status, visualizing the total number of data movements migrated versus those remaining. The dashboards tracked execution status, average runtime, and cost comparisons between the two connectors.
  • Dependency Tracking: Since the new system relied on a new set of APIs to fetch backup metadata, we implemented detailed metrics for failures to keep track of the APIs or dependencies failed.
  • Alerting: Proactive alerts were set up for job failures (Move Data or Casspactor), failures on Move Data that triggered a fallback to Casspactor or any data discrepancy being detected.

This comprehensive instrumentation allowed the team to be proactive, fix issues as they emerged during the migration, and gain the necessary confidence to accelerate the migration timeline.

Pillar 3: Safety

Even with perfect data correctness and enhanced visibility, the third pillar, Safety is required for a zero-impact migration. The challenge is ensuring that when a system inevitably fails, the user experience is uninterrupted. Our strategy centered on decoupling the user’s workflow from the underlying connector implementation.

Leveraging Abstraction: The Decider Pattern

To achieve a transparent swap, we leveraged the Maestro workflow orchestration platform to implement the Decider pattern:

  1. Data Movement Abstraction: From a user’s perspective, their Data Movement job definition remained the same.
  2. The Decider Step: Internally the workflow responsible to execute the job was modified to include a Decider step. This step took the data movement parameters (source cluster, table name, destination) and invoked a control plane: Connector Controller.
  3. Connector Controller as the Registry: The control plane served as the dynamic registry. Based on the migration cohort and the data movement attributes, it determined and reported the appropriate connector to use either Casspactor (legacy) or Move Data (new).

This abstraction gave our team complete control. We could upgrade or rollback any connector for any data movement instantly by simply updating a configuration in the controller, with zero modification required to the thousands of downstream customer workflows. Crucially, this abstraction guaranteed the critical safety net: a conditional step in the Maestro workflow logic ensured that if the Move Data step fails, it would immediately execute the Casspactor step.

This pattern would increase the chances that the user’s data movement completes successfully, even if the new connector encountered a bug or transient failure during the initial rollout phases. User impact was completely eliminated; they might see a slightly longer runtime in the event of a failure and fallback, but they would never see a migration failure or suffer from stale data.
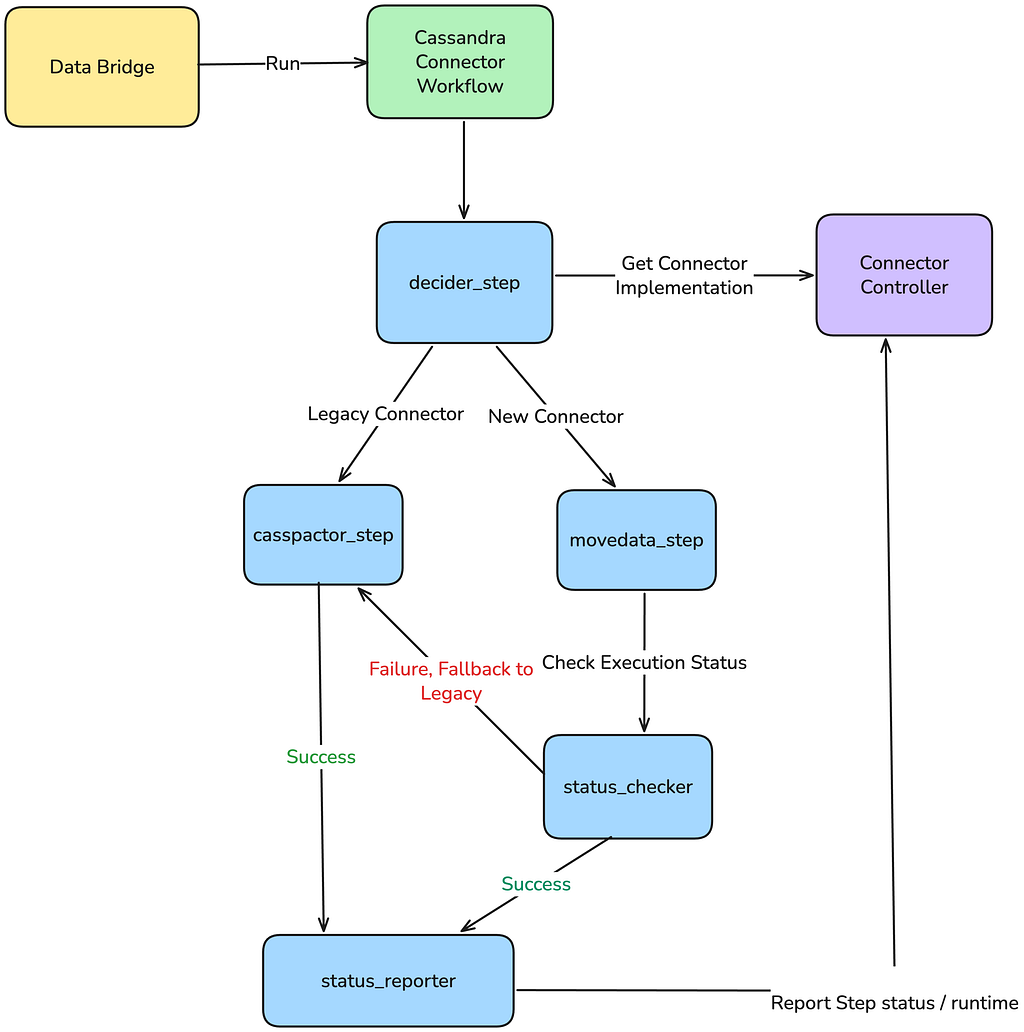
Image 5: The Decider Pattern Implementation via Maestro

Beyond the workflow, the new system architecture itself was inherently more resilient. By building the new data movement connector on Cassandra Analytics and reading backups directly from S3, we removed fragile dependencies on deprecated internal services.

Conclusion

The migration from Casspactor to the new, layered architecture built on Cassandra Analytics and the Move Data connector was more than a typical “tech debt” project; it was a fundamental shift in our approach to data movement reliability and scalability at Netflix.

The legacy system, while serving us well for years, was ultimately constrained by monolithic design, fragile metadata dependencies, and an inability to handle the complexity of modern data abstractions. The new stack resolves these issues by delivering a robust, cost-efficient, and inherently more resilient solution that reads directly from S3, handles wide partitions gracefully, and eliminates costly intermediate tables.

Our blueprint for the migration, anchored by the three pillars of Validation, Visibility, and Safety, ensured a transparent and high-confidence transition. Through rigorous shadow testing and a data-driven audit framework, we achieved the desired data consistency. Enhanced dashboards and alerting provided the real-time operational insight necessary to manage risk. Most critically, the implementation of the Decider pattern within our workflow abstraction minimized the impact for all downstream users.

This successful migration validates a core philosophy: by abstracting complexity at the platform level, we can perform large system migrations without burdening our product engineering partners. The new foundation is now ready to support the next generation of Netflix’s data abstractions.

Looking ahead

This foundational work on the Cassandra Data Movement stack has done more than just replace a legacy system: it has become an accelerator for innovation across the entire Data Movement organization. By providing a reliable, performant engine that standardizes data retrieval into Spark DataFrames, we’ve enabled the rapid development of new, highly optimized connectors. This new “Connector Factory” approach has already delivered a dedicated Key-Value to Iceberg and Time Series connectors, both of which are fully aware of their respective data models, eliminating costly post-processing. This architecture is also paving the way for ambitious new initiatives, including the development of a solution for bulk loading data into Cassandra itself, effectively completing the data movement cycle, and enabling safer fleetwide connector rollout with canaries inspired by the Decider Pattern.

We are incredibly grateful for the extensive collaboration among the Data Movement, Data Bridge, Online Data Stores, Membership, Billing, Subscriber and Ads platform teams at Netflix; this work simply couldn’t have been accomplished without their partnership!


The Evolution of Cassandra Data Movement at Netflix was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.

Data Movement in Netflix Studio via Data Mesh

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/data-movement-in-netflix-studio-via-data-mesh-3fddcceb1059

By Andrew Nguonly, Armando Magalhães, Obi-Ike Nwoke, Shervin Afshar, Sreyashi Das, Tongliang Liu, Wei Liu, Yucheng Zeng

Background

Over the next few years, most content on Netflix will come from Netflix’s own Studio. From the moment a Netflix film or series is pitched and long before it becomes available on Netflix, it goes through many phases. This happens at an unprecedented scale and introduces many interesting challenges; one of the challenges is how to provide visibility of Studio data across multiple phases and systems to facilitate operational excellence and empower decision making. Netflix is known for its loosely coupled microservice architecture and with a global studio footprint, surfacing and connecting the data from microservices into a studio data catalog in real time has become more important than ever.

Operational Reporting is a reporting paradigm specialized in covering high-resolution, low-latency data sets, serving detailed day-to-day activities¹ and processes of a business domain. Such a paradigm aspires to assist front-line operations personnel and stakeholders in “running the business”²; performing their tasks through means such as ad hoc analysis, decision-support, and tracking (of tasks, assets, schedules, etc). The paradigm spans across methods, tools, and technologies and is usually defined in contrast to analytical reporting and predictive modeling which are more strategic (vs. tactical) in nature.

At Netflix Studio, teams build various views of business data to provide visibility for day-to-day decision making. With dependable near real-time data, Studio teams are able to track and react better to the ever-changing pace of productions and improve efficiency of global business operations using the most up-to-date information. Data connectivity across Netflix Studio and availability of Operational Reporting tools also incentivizes studio users to avoid forming data silos.

The Journey

In the past few years, Netflix Studio has gone through few iterations of data movement approaches. In the initial stage, data consumers set up ETL pipelines directly pulling data from databases. With this batch style approach, several issues have surfaced like data movement is tightly coupled with database tables, database schema is not an exact mapping of business data model, and data being stale given it is not real time etc. Later on, we moved to event driven streaming data pipelines (powered by Delta), which solved some problems compared to the batch style, but had its own pain points, such as a high learning curve of stream processing technologies, manual pipeline setup, a lack of schema evolution support, inefficiency of onboarding new entities, inconsistent security access models, etc.

With the latest Data Mesh Platform, data movement in Netflix Studio reaches a new stage. This configuration driven platform decreases the significant lead time when creating a new pipeline, while offering new support features like end-to-end schema evolution, self-serve UI and secure data access. The high level diagram below indicates the latest version of data movement for Operational Reporting.

Operational Reporting Architecture Overview

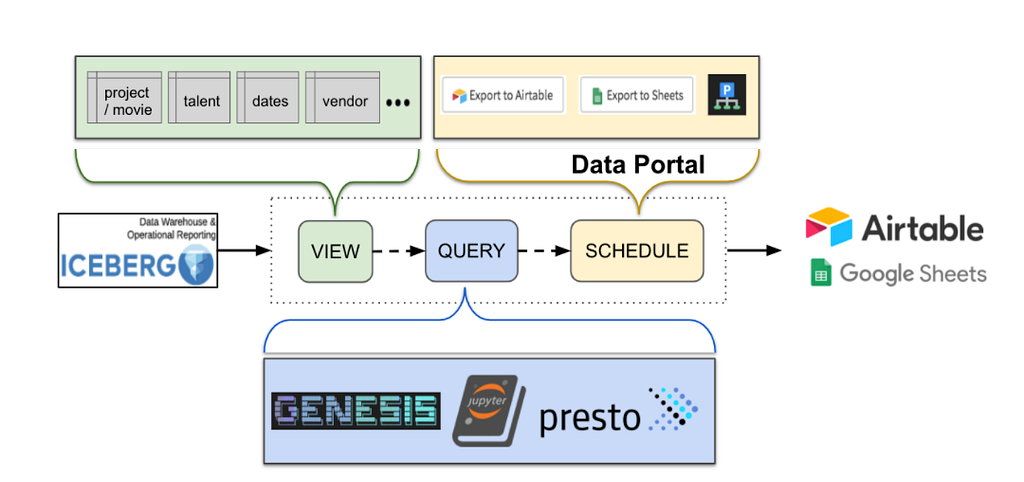
For data delivery, we leverage the Data Mesh platform to power the data movement. Netflix Studio applications expose GraphQL queries via Studio Edge, which is a unified graph that connects all data in Netflix Studio and provides consistent data retrieval. Change Data Capture(CDC) source connector reads from studio applications’ database transaction logs and emits the change events. The CDC events are passed on to the Data Mesh enrichment processor, which issues GraphQL queries to Studio Edge to enrich the data. Once the data has landed in the Iceberg tables in Netflix Data Warehouse, they could be used for ad-hoc or scheduled querying and reporting. Centralized data will be moved to third party services such as Google Sheets and Airtable for the stakeholders. We will deep dive into Data Delivery and Data Consumption in the following sections.

Data Delivery via Data Mesh

What is Data Mesh?

Data Mesh is a fully managed, streaming data pipeline product used for enabling Change Data Capture (CDC) use cases. In Data Mesh, users create sources and construct pipelines. Sources mimic the state of an externally managed source — as changes occur in the external source, corresponding CDC messages are produced to the Data Mesh source. Pipelines can be configured to transform and store data to externally managed sinks.

Data Mesh provides a drag-and-drop, self-service user interface for exploring sources and creating pipelines so that users can focus on delivering business value without having to worry about managing and scaling complex data streaming infrastructure.

CDC and data source

Change data capture or CDC, is a semantic for processing changes in a source for the purpose of replicating those changes to a sink. The table changes could be row changes (insert row, update row, delete row) or schema changes (add column, alter column, drop column). As of now, CDC sources have been implemented for data stores at Netflix (MySQL, Postgres). CDC events can also be sent to Data Mesh via a Java Client Producer Library.

Reusable Processors and Configuration Driven

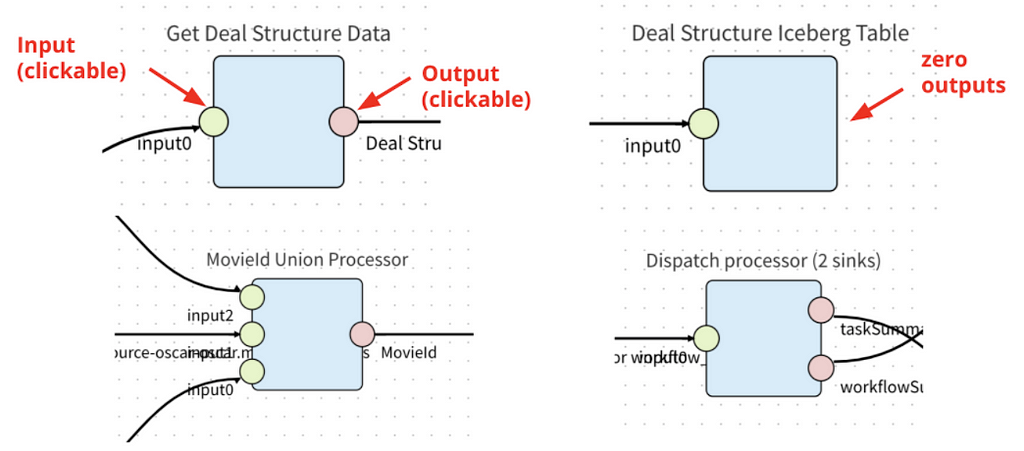
In Data Mesh, a processor is a configurable data processing application that consumes, transforms, and produces CDC events. A processor has 1 or more inputs and 0 or more outputs. Processors with 0 outputs are sink connectors; which write events to externally managed sinks (e.g. Iceberg, ElasticSearch, etc).

Processors with Different Inputs/Outputs

Data Mesh allows developers to contribute processors to the platform. Processors are not necessarily centrally developed and managed. However, the Data Mesh platform team strives to provide and manage the most highly leveraged processors (e.g. source connectors and sink connectors)

Processors are reusable. The same processor image package is used multiple times for all instances of the processor. Each instance is configured to fit each use case. For example, a GraphQL enrichment processor can be provisioned to query GraphQL Services to enrich data in different pipelines; an Iceberg sink processor can be initialized multiple times to write data to different databases/tables with different schema.

End-to-End Schema Evolution

Schema is a key component of Data Mesh. When an upstream schema evolves (e.g. schema change in the MySQL table), Data Mesh detects the change, checks the compatibility and applies the change to the downstream. With schema evolution, Data Mesh ensures the Operational Reporting pipelines always produce data with the latest schema.

We will cover a few core concepts in the Data Mesh Schema domain.

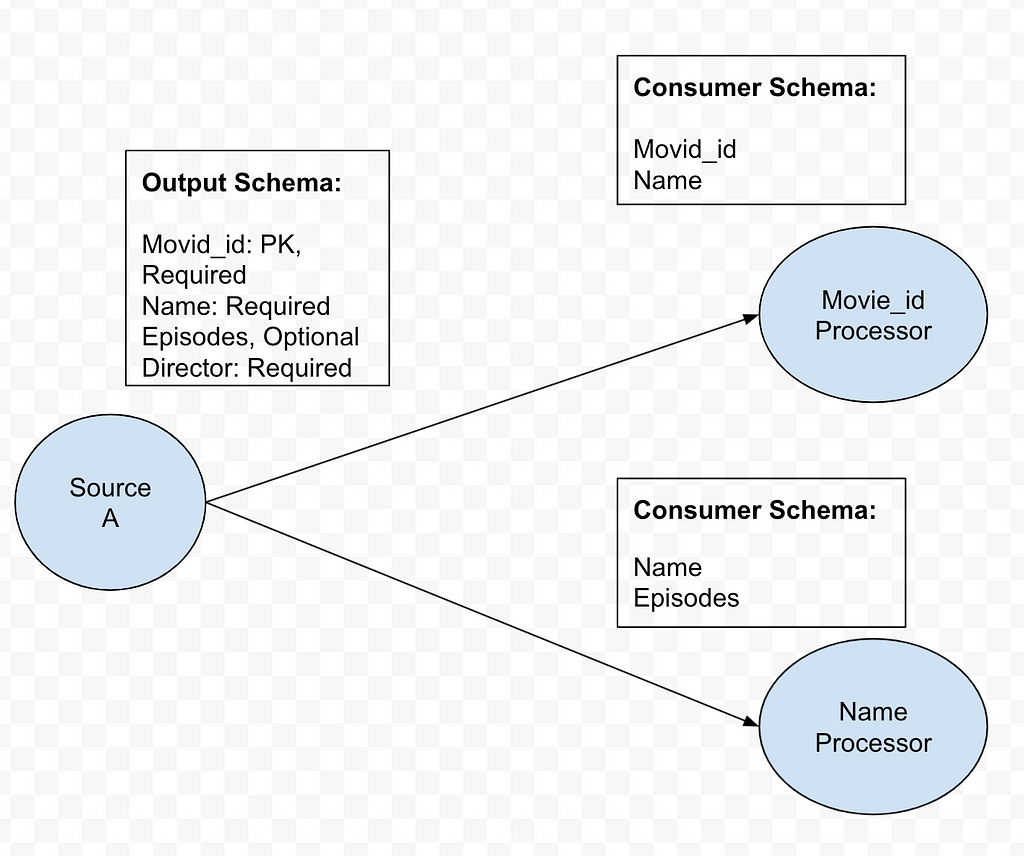
Consumer schema
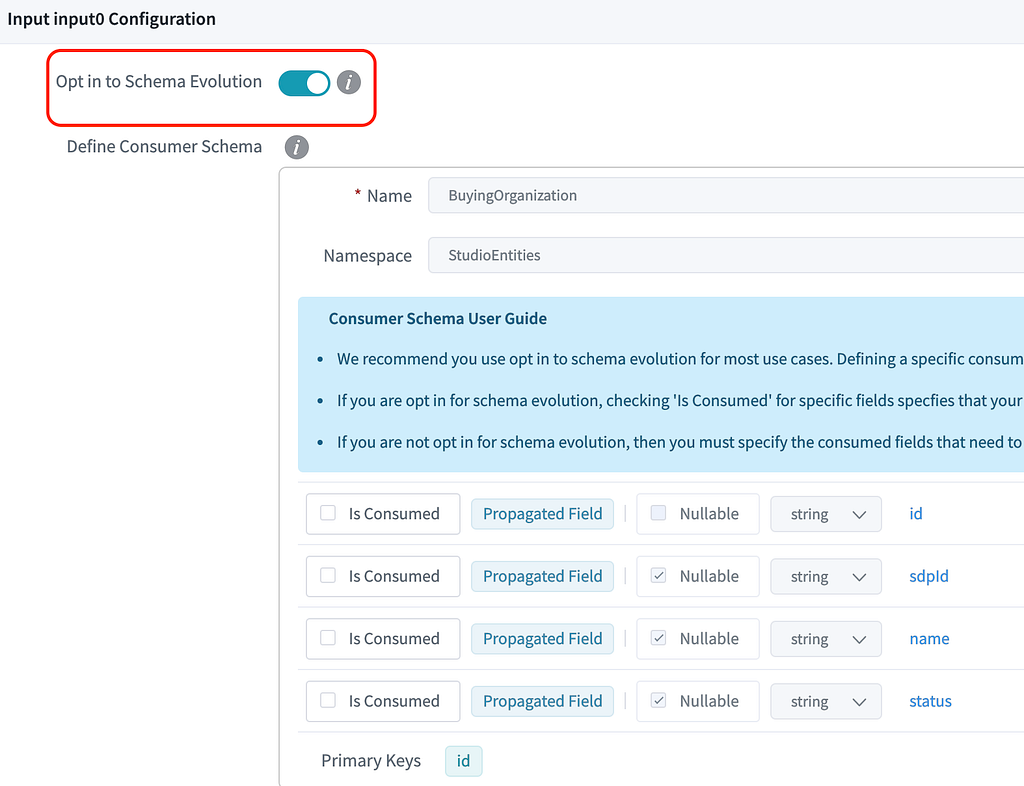
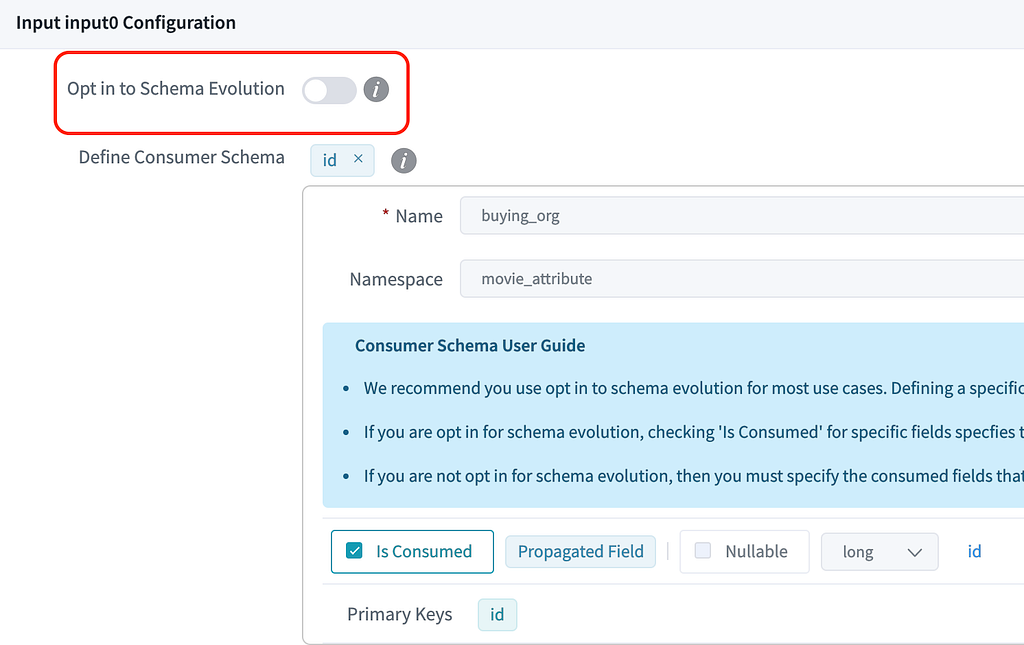
Consumer schema defines how data is consumed by the downstream processors. See example below.

Consumer Schema Example
Consumer Schema Example

Schema Compatibility
Data Mesh uses Consumer Schema compatibility to achieve flexible yet safe schema evolution. If a field consumed by an Operational Reporting pipeline is removed from CDC source, Data Mesh categorizes this change as incompatible, pauses the pipeline processing and notifies the pipeline owner. On the other hand, if a required field is not consumed by any consumer, dropping such fields would be compatible.

Two Types of Processors
1. Pass through all fields from upstream to downstream.

  • Example: Filter Processor, Sink Processors
Opt in to schema Evolution example

2. Only uses a subset of fields from upstream.

  • Example: Project Processor, Enrichment Processor
Opt out to schema Evolution example

In Data Mesh, we introduce the Opt-in to Schema Evolution boolean flag to differentiate those two types of use cases.

  • Opt in: All the upstream fields will be propagated to the processor. For example, when a new field is added upstream, it will be propagated automatically.
  • Opt out: Only a subset of fields (defined using ‘Is Consumed’ checkboxes) is propagated and used in the processor. Upstream changes to the rest of the fields won’t affect this processor.

Schema Propagation
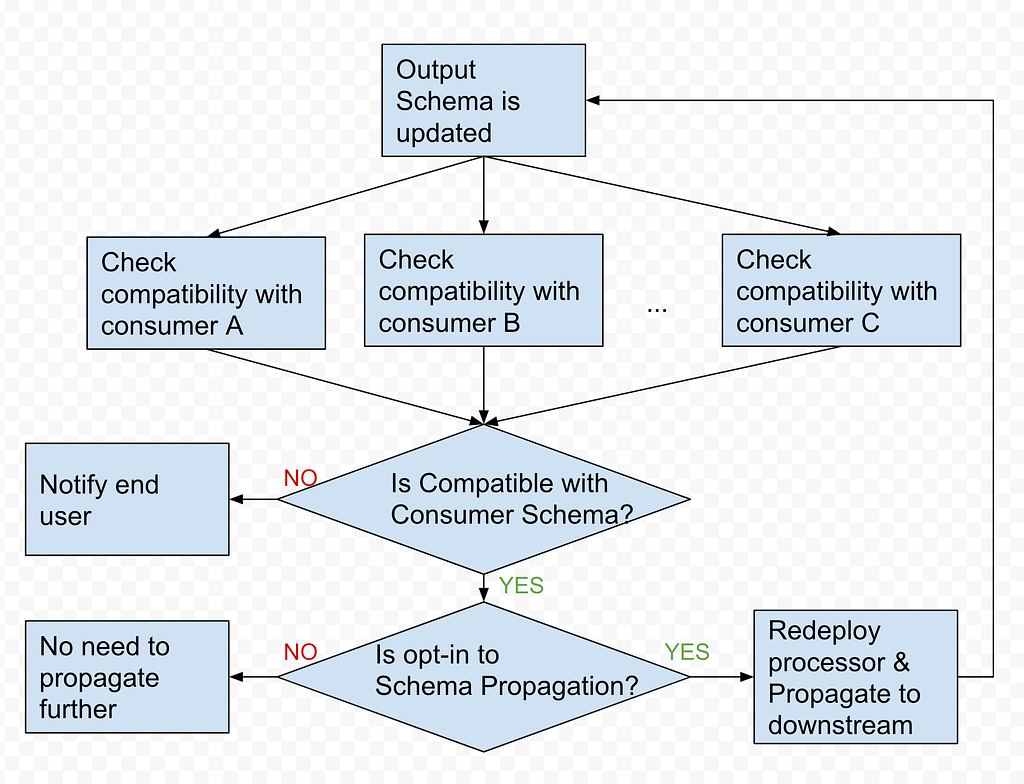
After the Schema Compatibility is checked, Data Mesh Platform will propagate the schema change based on the end user’s intention. With the opt-in to schema Evolution flag, Operational Reporting pipelines can keep the schema up-to-date with upstream data stores. As part of schema propagation, the platform also syncs the schema from the pipeline to the Iceberg sink.

Schema Evolution Diagram

Enrichment Processor via GraphQL

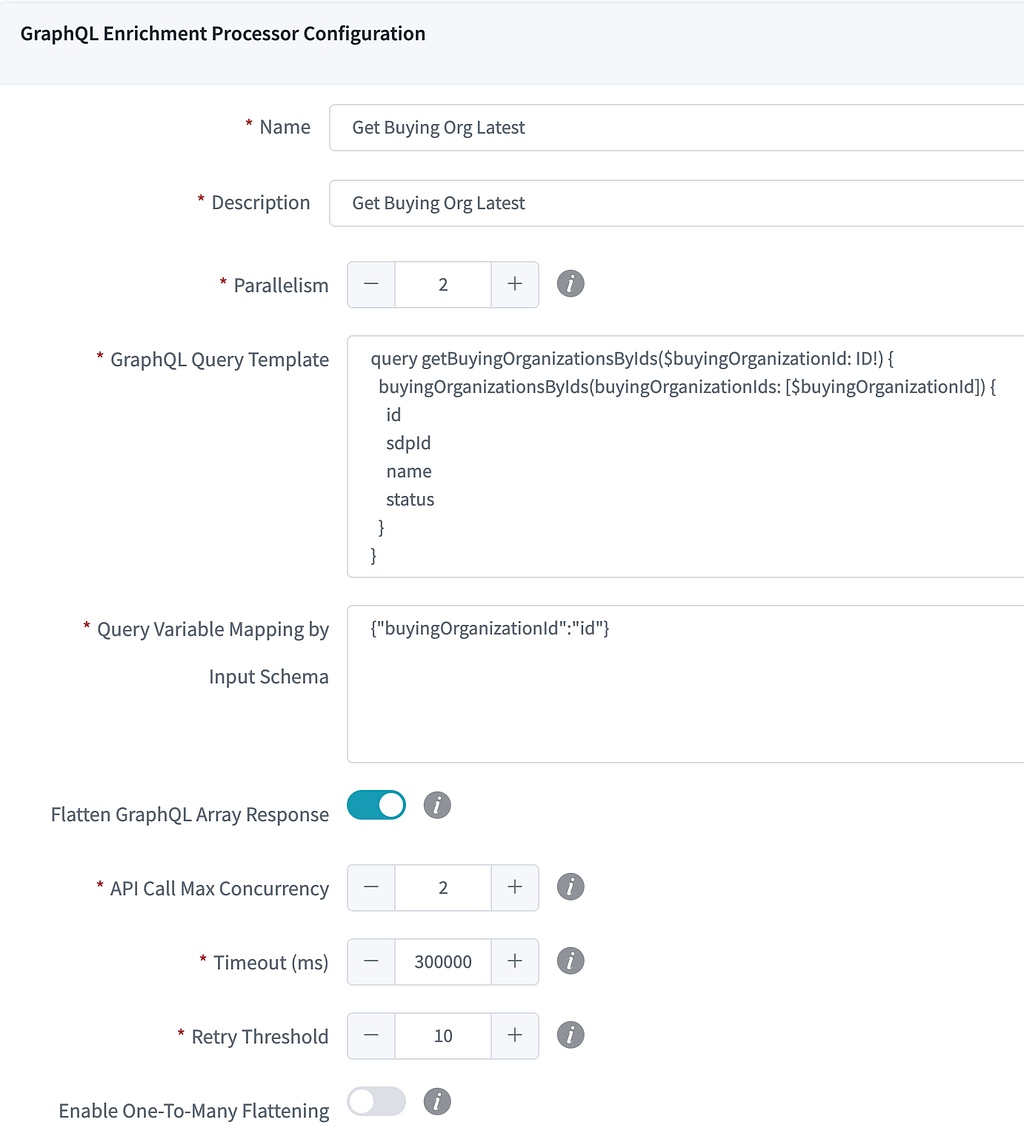
In the current Data Mesh Operational Reporting pipelines, the most commonly used intermediate processor is the GraphQL Enrichment Processor. It takes in the column value from CDC events coming from Source Connector as GraphQL query input, then submits a query to Studio Edge to enrich the data. With Studio Edge’s single data model, it centralizes data modeling efforts, which is highly leveraged by Studio UI Apps, Backend services and Search platforms. Enriching the data via Studio Edge helps us achieve consistent data modeling across the whole ecosystem for Operational Reporting.

Here is the example of GraphQL processor configuration, pipeline builder only need config the following fields to provision an enrichment processor:

GraphQL Enrichment Processor Configuration Example

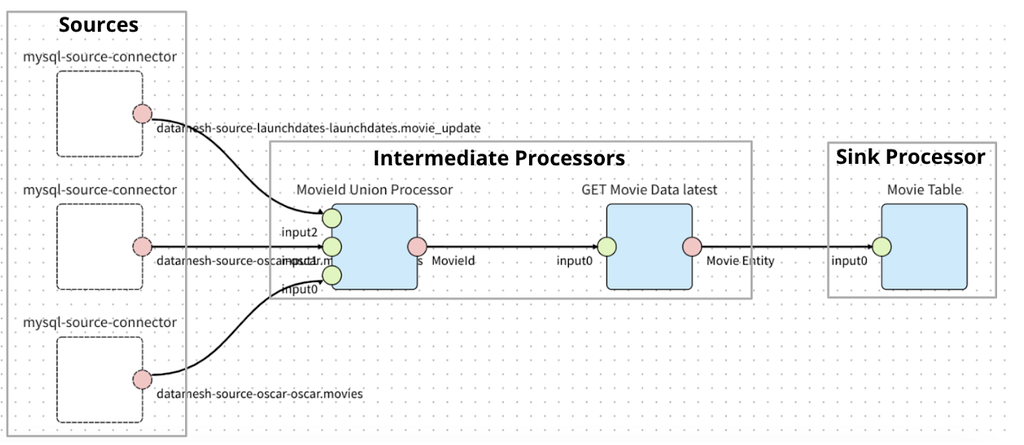
The image below is a sample Operational Reporting pipeline in the production environment to sink the Movie related data. Teams who want to move their data no longer need to learn and write customized Stream Processing jobs. Instead they just need to configure the pipeline topology in the UI while getting other features like schema evolution and secure data access out of the box.

Operational Reporting Pipeline Example

Iceberg Sink

Apache Iceberg is an open source table format for huge analytics datasets. Data Mesh leverages Iceberg tables as data warehouse sinks for downstream analytics use cases. Currently Iceberg sink is appended only. Views are built on top of the raw Iceberg tables to retrieve the latest record for every primary key based on the operational timestamp, which indicates when the record is produced in the sink. Current pipeline consumers are directly consuming Views instead of raw tables.

The compaction process is needed to optimize the performance of downstream queries on the business view as well as lower costs of S3 GET OBJECT operations. A daily process ranks the records by timestamp to generate a data frame of compacted records. Old data files are overwritten with a set of new data files that contain only the compacted data.

Data Quality

Data Mesh provides metrics and dashboards at both the processor and pipeline level for operational observability. Operational Reporting pipeline owners will get alerts if something goes wrong with their pipelines. We also have two types of auditing on the data tables generated from Data Mesh pipelines to guarantee data quality: end-to-end auditing and synthetic events.

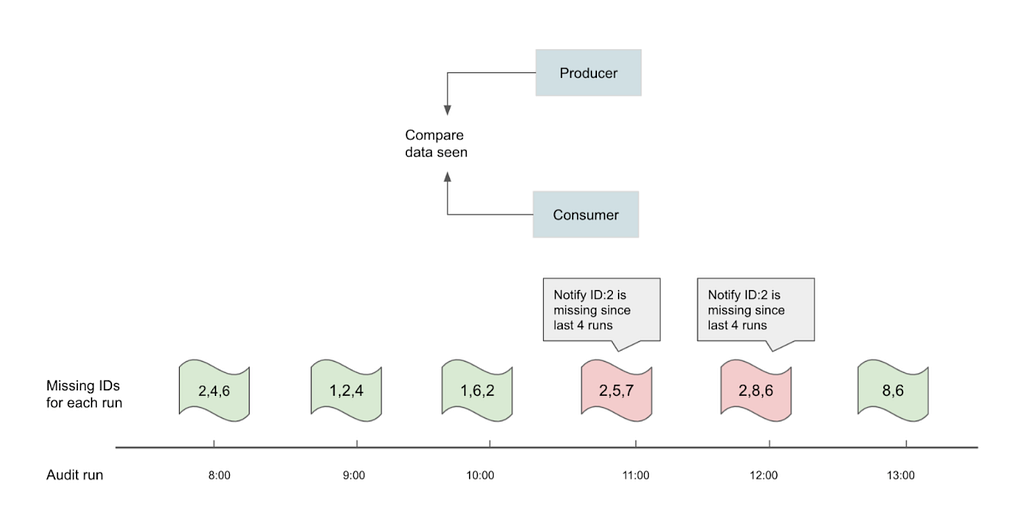
Most of the business views created on top of the Iceberg tables can tolerate a few minutes of latency. However, it is paramount that we validate the complete set of identifiers such as a list of movie ids across producers and consumers for higher overall confidence in the data transport layer of choice. For end-to-end audits, the objective is to run the audits hourly via Big data Platform Scheduler, which is a centralized and integrated tool provided by Netflix data platform for running workflows in an efficient, reliable and reproducible way. The audits check for equality (i.e. query results should be the same), the symmetric difference between two data sets should be empty across multiple runs, and the eventual consistency within the SLA. An hourly notification is sent when a set of primary keys consistently do not match between source of truth and target Data Mesh tables.

End to End (Black Box) Auditing Example

Synthetic events audits are artificially triggered change events to imitate common CUD operations of services. It is generating heartbeat signals at a constant frequency with the objective of using them as a baseline to verify the health of the pipeline regardless of traffic patterns or occasional silences.

Data Consumption

Our studio partners rely on data to make informed decisions and to collaborate during all the phases related to production. The Studio Tech Solutions team provides near real-time reports in some data tool of choice, which we call trackers to empower the decision making.

For the past few years, many of these trackers were powered by hand-curated SQL scripts and API calls being managed by CRON schedulers implemented in a Java Service called Lego. Lego was the main tool for the STS team, and at its peak, Lego managed 300+ trackers.

This strategy had its own set of challenges: being schema-less and treating every report column like a string not always worked out, the volatile reliance on direct RDS connections and rate limits from third party APIs would often make jobs fail. We had a set of “core views” which would be specifically tailored for reports, but this caused queries that just required a very small subset of fields to be slow and expensive due to the view doing a huge amount of joining and aggregation work before being able to retrieve that small subset.

Besides the issues, this worked fine when we didn’t have many trackers to maintain, but as we created more trackers to the point of having many hundreds, we started having issues around maintenance, awareness, knowledge sharing and standardization. New team members had a hard time getting onboard, figuring out which SQL powered which tracker was tough, the lack of standards made every SQL look different and having to update trackers as the data sources changed was a nightmare.

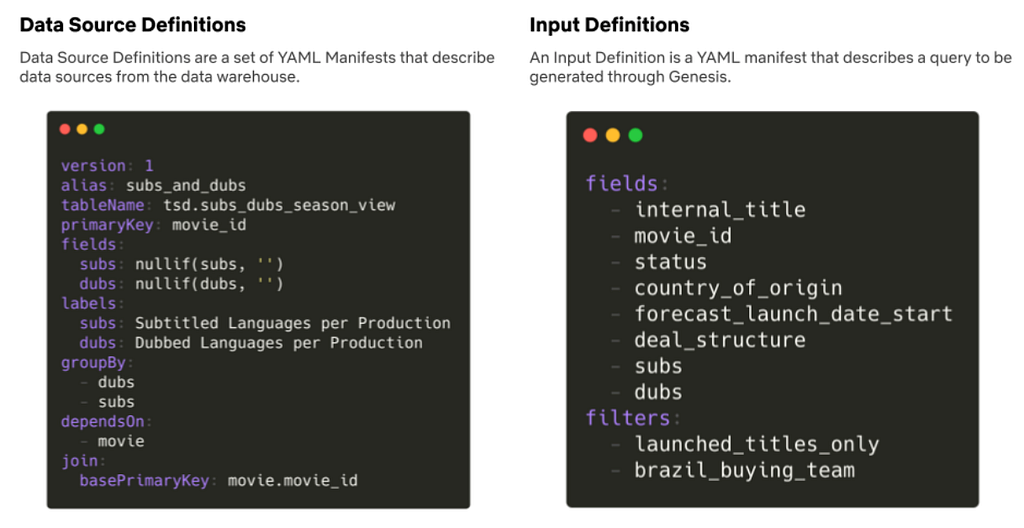
With this in mind, the Studio Tech Solutions focused efforts in building Genesis, a Semantic Data Layer that allows the team to map data points in Data Source Definitions defined as YAML files and then use those to generate the SQL needed for the trackers, based on a selection of fields, filters and formatters specified in an Input Definition file. Genesis takes care of joining, aggregating, formatting and filtering data based on what is available in the Data Source Definitions and specified by the user through the Input Definition being executed.

Genesis Data Source and Input definition example

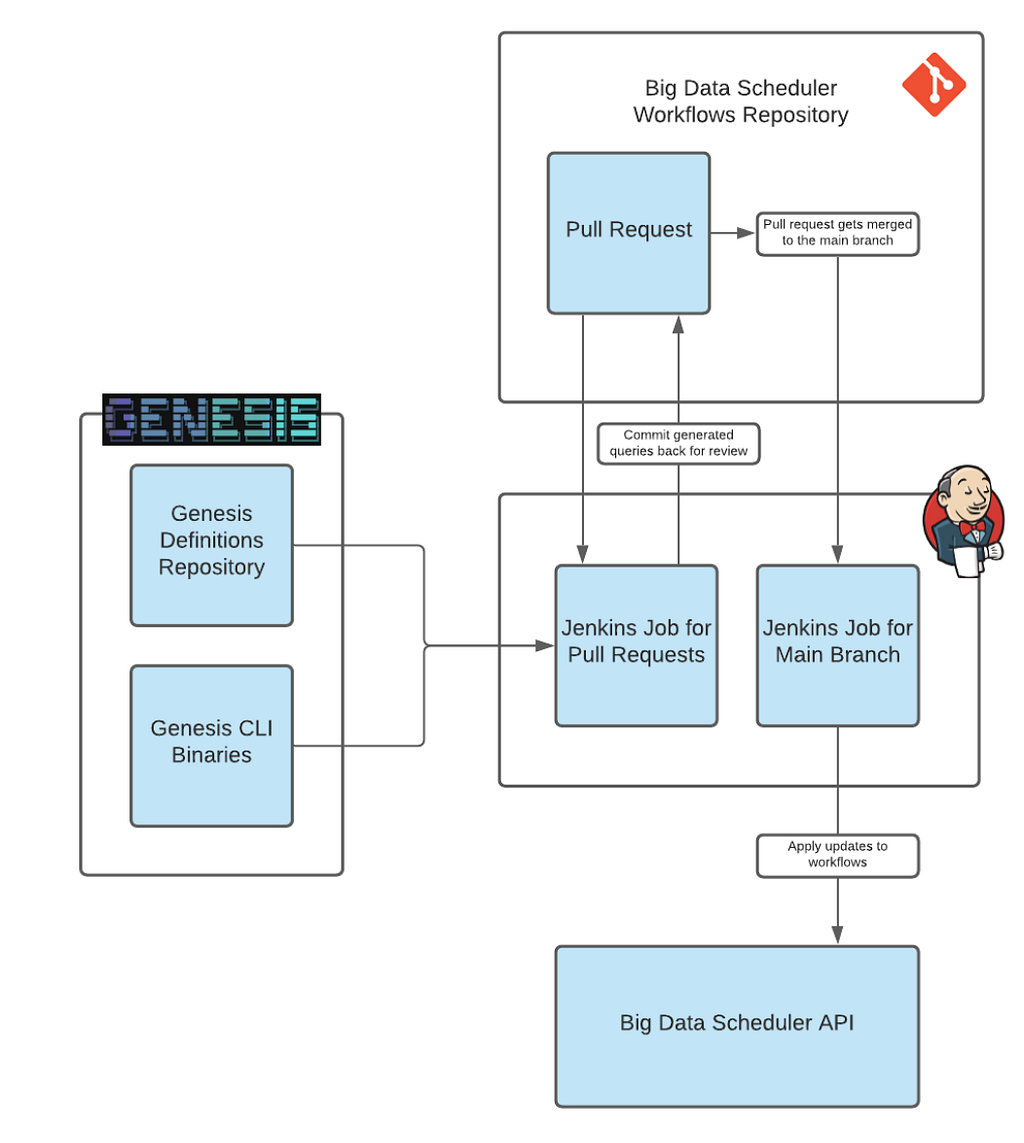
Genesis is a stateless CLI written in Node.js that reads everything it needs from the file system based on the paths specified in the arguments. This allows us to hook Genesis into Jenkins Jobs, providing a GitOps and CI experience to maintain existing trackers, as well as create new trackers. We can simply change the data layer, trigger an empty pull request, review the changes and have all our trackers up to date with the data source changes.

As of the date of writing, Genesis powers 240+ trackers and is growing everyday, empowering thousands of partners in our studios globally to collaborate, annotate and share information using near-real-time data.

Git-based Tracker management workflow powered by Genesis and the Big Data Scheduler

The generated queries are then used in Workflow Definitions for multiple trackers. The Netflix Data Warehouse offers support for users to create data movement workflows that are managed through our Big Data Scheduler, powered by Titus.

We use the scheduler to execute our queries and move the results to a data tool, which often is a Google Sheet Tab, Airtable base or Tableau dashboard. The scheduler offers templated jobs for moving data from a Presto SQL output to these tools, making it easy to create and maintain hundreds of data movement workflows.

The diagram below summarizes the data consumption flow when building trackers:

Data Consumption Overview

As of July 2021, the Studio Tech Solutions team is finishing a migration from all the trackers built in Lego to use Genesis and the Data Portal. This strategy has increased the Studio Tech Solutions team performance and stability. Trackers are now easy for the team to create, review, change, monitor and discover.

Now and Future

In conclusion, our studio partners have a tracker available to them, populated with near real-time data and tailored to their needs. They can manipulate, annotate, and collaborate using a flexible tool they are familiar with.

Along the journey, we have learned that evolving data movement in complex domains could take multiple iterations and needs to be driven by the business impact. The great cross-functional partnership and collaboration among all data stakeholders is crucial to shape the ideal data product.

However, our story doesn’t end here. We still have a long journey ahead of us to fulfill the vision of such ideal data product, especially in areas such as:

  • Self-servicing data pipelines provisioning via configuration
  • Providing toolings for data discoverability, understandability, usage visibility and change management
  • Enabling data domain orientation and ownership/governance management
  • Bootstrapping trackers in our Studio ecosystem instead of third party tools. Along the same line as the point above, this would allow us to maintain high standards of data governance, lineage, and security.
  • Read-write reports and trackers using GraphQL mutations

These are some of the interesting areas that Netflix Studio is planning to invest in. We will have follow up blog posts on these topics in future. Please stay tuned!

Endnotes

¹ Inmon, Bill. Operational and Informational Reporting, Information Management, July 1st, 2000.
² Dehghani, Zhamak. Data Mesh: Delivering Data-driven Value at Scale, O’Reilly Media, Inc., 2021.

Acknowledgements

Data Movement via Data Mesh has been a success in Netflix Studio owing to multiple teams’ efforts. We would like to acknowledge the following colleagues: Amanda Benhamou, Andreas Andreakis, Anthony Preza, Bo Lei, Charles Zhao, Justin Cunningham, Kasturi Chatterjee, Kevin Zhu, Stephanie Barreyro, Yoomi Koh.


Data Movement in Netflix Studio via Data Mesh was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.
Bulldozer: Batch Data Moving from Data Warehouse to Online Key-Value Stores

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/bulldozer-batch-data-moving-from-data-warehouse-to-online-key-value-stores-41bac13863f8

By Tianlong Chen and Ioannis Papapanagiotou

Netflix has more than 195 million subscribers that generate petabytes of data everyday. Data scientists and engineers collect this data from our subscribers and videos, and implement data analytics models to discover customer behaviour with the goal of maximizing user joy. Usually Data scientists and engineers write Extract-Transform-Load (ETL) jobs and pipelines using big data compute technologies, like Spark or Presto, to process this data and periodically compute key information for a member or a video. The processed data is typically stored as data warehouse tables in AWS S3. Iceberg is widely adopted in Netflix as a data warehouse table format that addresses many of the usability and performance problems with Hive tables.

At Netflix, we also heavily embrace a microservice architecture that emphasizes separation of concerns. Many of these services often have the requirement to do a fast lookup for this fine-grained data which is generated periodically. For example, in order to enhance our user experience, one online application fetches subscribers’ preferences data to recommend movies and TV shows. The data warehouse is not designed to serve point requests from microservices with low latency. Therefore, we must efficiently move data from the data warehouse to a global, low-latency and highly-reliable key-value store. For how our machine learning recommendation systems leverage our key-value stores, please see more details on this presentation.

What is Bulldozer

Bulldozer is a self-serve data platform that moves data efficiently from data warehouse tables to key-value stores in batches. It leverages Netflix Scheduler for scheduling the Bulldozer Jobs. Netflix Scheduler is built on top of Meson which is a general purpose workflow orchestration and scheduling framework to execute and manage the lifecycle of the data workflow. Bulldozer makes data warehouse tables more accessible to different microservices and reduces each individual team’s burden to build their own solutions. Figure 1 shows how we use Bulldozer to move data at Netflix.

Figure 1. Moving data with Bulldozer at Netflix.

As the paved path for moving data to key-value stores, Bulldozer provides a scalable and efficient no-code solution. Users only need to specify the data source and the destination cluster information in a YAML file. Bulldozer provides the functionality to auto-generate the data schema which is defined in a protobuf file. The protobuf schema is used for serializing and deserializing the data by Bulldozer and data consumers. Bulldozer uses Spark to read the data from the data warehouse into DataFrames, converts each data entry to a key-value pair using the schema defined in the protobuf and then delivers key-value pairs into a key-value store in batches.

Instead of directly moving data into a specific key-value store like Cassandra or Memcached, Bulldozer moves data to a Netflix implemented Key-Value Data Abstraction Layer (KV DAL). The KV DAL allows applications to use a well-defined and storage engine agnostic HTTP/gRPC key-value data interface that in turn decouples applications from hard to maintain and backwards-incompatible datastore APIs. By leveraging multiple shards of the KV DAL, Bulldozer only needs to provide one single solution for writing data to the highly abstracted key-value data interface, instead of developing different plugins and connectors for different data stores. Then the KV DAL handles writing to the appropriate underlying storage engines depending on latency, availability, cost, and durability requirements.

Figure 2. How Bulldozer leverages Spark, Protobuf and KV DAL for moving the data.

Configuration-Based Bulldozer Job

For batch data movement in Netflix, we provide job templates in our Scheduler to make movement of data from all data sources into and out of the data warehouse. Templates are backed by notebooks. Our data platform provides the clients with a configuration-based interface to run a templated job with input validation.

We provide the job template MoveDataToKvDal for moving the data from the warehouse to one Key-Value DAL. Users only need to put the configurations together in a YAML file to define the movement job. The job is then scheduled and executed in Netflix Big Data Platform. This configuration defines what and where the data should be moved. Bulldozer abstracts the underlying infrastructure on how the data moves.

Let’s look at an example of a Bulldozer YAML configuration (Figure 3). Basically the configuration consists of three major domains: 1) data_movement includes the properties that specify what data to move. 2) key_value_dal defines the properties of where the data should be moved. 3) bulldozer_protobuf has the required information for protobuf file auto generation.

Figure 3. An Exemplar Bulldozer Job YAML.

In the data_movement domain, the source of the data can be a warehouse table or a SQL query. Users also need to define the key and value columns to tell Bulldozer which column is used as the key and which columns are included in the value message. We will discuss more details about the schema mapping in the next Data Model section. In the key_value_dal domain, it defines the destination of the data which is a namespace in the Key-Value DAL. One namespace in a Key-Value DAL contains as many key-value data as required, it is the equivalent to a table in a database.

Data Model

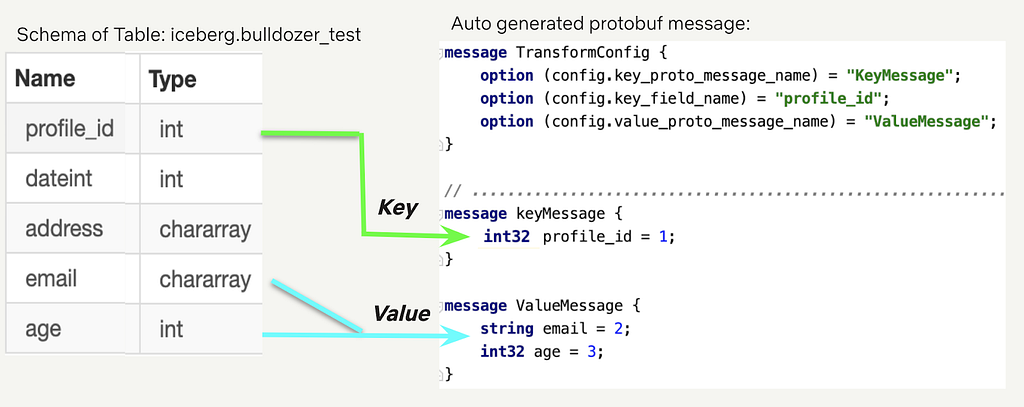
Bulldozer uses protobuf for 1) representing warehouse table schema into a key-value schema; 2) serializing and deserializing the key-value data when performing write and read operations to KV DAL. In this way, it allows us to provide a more traditional typed record store while keeping the key-value storage engine abstracted.

Figure 4 shows a simple example of how we represent a warehouse table schema into a key-value schema. The left part of the figure shows the schema of the warehouse table while the right part is the protobuf message that Bulldozer auto generates based on the configurations in the YAML file. The field names should exactly match for Bulldozer to convert the structured data entries into the key-value pairs. In this case, profile_id field is the key while email and age fields are included in the value schema. Users can use the protobuf schema KeyMessage and ValueMessage to deserialize data from Key-Value DAL as well.

Figure 4. An Example of Schema Mapping.

In this example, the schema of the warehouse table is flat, but sometimes the table can have nested structures. Bulldozer supports complicated schemas, like struct of struct type, array of struct, map of struct and map of map type.

Data Version Control

Bulldozer jobs can be configured to execute at a desired frequency of time, like once or many times per day. Each execution moves the latest view of the data warehouse into a Key-Value DAL namespace. Each view of the data warehouse is a new version of the entire dataset. For example, the data warehouse has two versions of full dataset as of January 1st and 2nd, Bulldozer job is scheduled to execute daily for moving each version of the data.

Figure 5. Dataset of January 1st 2020.
Figure 6. Dataset of January 2nd 2020.

When Bulldozer moves these versioned data, it usually has the following requirements:

  • Data Integrity. For one Bulldozer job moving one version of data, it should write the full dataset or none. Partially writing is not acceptable. For example above, if the consumer reads value for movie_id: 1 and movie_id: 2 after the Bulldozer jobs, the returned values shouldn’t come from two versions, like: (movie_id: 1, cost 40), (movie_id: 2, cost 101).
  • Seamless to Data Consumer. Once a Bulldozer job finishes moving a new version of data, the data consumer should be able to start reading the new data automatically and seamlessly.
  • Data Fallback. Normally, data consumers read only the latest version of the data, but if there’s some data corruption in that version, we should have a mechanism to fallback to the previous version.

Bulldozer leverages the KV DAL data namespace and namespace alias functionality to manage these versioned datasets. For each Bulldozer job execution, it creates a new namespace suffixed with the date and moves the data to that namespace. The data consumer reads data from an alias namespace which points to one of these version namespaces. Once the job moves the full data successfully, the Bulldozer job updates the alias namespace to point to the new namespace which contains the new version of data. The old namespaces are closed to reads and writes and deleted in the background once it’s safe to do so. As most key-value storage engines support efficiently deleting a namespace (e.g. truncate or drop a table) this allows us to cheaply recycle old versions of the data. There are also other systems in Netflix like Gutenberg which adopt a similar namespace alias approach for data versioning which is applied to terabyte datasets.

For example, in Figure 7 data consumers read the data through namespace: alias_namespace which points to one of the underlying namespaces. On January 1st 2020, Bulldozer job creates namespace_2020_01_01 and moves the dataset, alias_namespace points to namespace_2020_01_01. On January 2nd 2020, there’s a new version of data, bulldozer creates namespace_2020_01_02 , moves the new dataset and updates alias_namespace pointing to namespace_2020_01_02. Both namespace_2020_01_01 and namespace_2020_01_02 are transparent to the data consumers.

Figure 7. An Example of How the Namespace Aliasing Works.

The namespace aliasing mechanism ensures that the data consumer only reads data from one single version. If there’s a bad version of data, we can always swap the underlying namespaces to fallback to the old version.

Production Usage

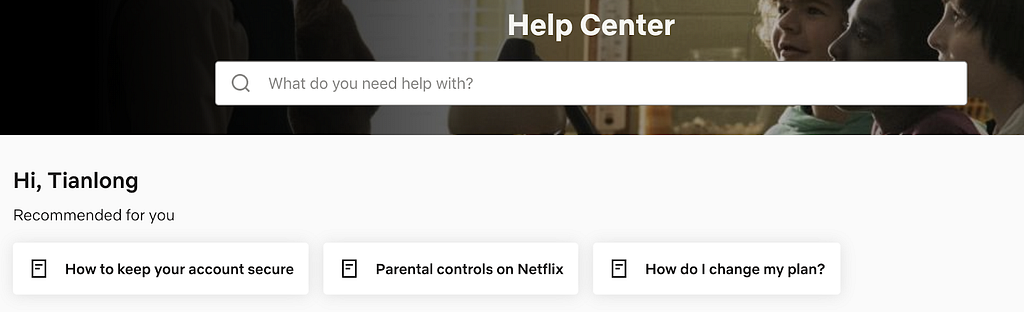
We released Bulldozer in production in early 2020. Currently, Bulldozer transfers billions of records from the data warehouse to key-value stores in Netflix everyday. The use cases include our members’ predicted scores data to help improve personalized experience (one example shows in Figure 8), the metadata of Airtable and Google Sheets for data lifecycle management, the messaging modeling data for messaging personalization and more.

Figure 8. Personalized articles in Netflix Help Center powered by Bulldozer.

Stay Tuned

The ideas discussed here include only a small set of problems with many more challenges still left to be identified and addressed. Please share your thoughts and experience by posting your comments below and stay tuned for more on data movement work at Netflix.


Bulldozer: Batch Data Moving from Data Warehouse to Online Key-Value Stores was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.