There’s a familiar tension in enterprise technology: buy a fully integrated platform or assemble a stack of best-of-breed components. The platform story is compelling: one vendor. One console. One contract. Everything bundled together.
The best-of-breed story is different. Best-of-breed optimizes each layer for performance, flexibility, and cost. Historically, platforms often won the narrative. But in periods of rapid change—like today’s AI era—modularity regains the advantage.
The platform gravity problem
Platforms can introduce operational gravity. When compute, storage, networking, analytics, governance, and AI tooling all live in one ecosystem, switching costs rise over time. What starts as convenience becomes constraint—and in AI, where tooling changes rapidly, that becomes expensive in both flexibility and economics. Industry leaders reflect this shift. CIOs are moving beyond a “cloud-first” mindset toward “cloud-smart” strategies and choosing the right environment for each workload instead of defaulting to one provider’s stack. This proactively avoids escalating costs and inflexible ecosystems. A recent CIO Dive trend report finds many IT leaders are gravitating toward purpose-built infrastructure optimized for specific workload demands—including AI—rather than broad commodity offerings.
Why modular infrastructure wins
AI pipelines evolve constantly: training datasets, checkpoints, GPU migrations, MLOps workflows and post-processing outputs are all subject to rapid changes to scale applications and extend model capabilities. Few organizations run all of that inside a single vendor environment or a single cloud ecosystem. Teams building differentiated systems optimize workflows and resources, not monoliths.
Modularity isn’t just about avoiding lock-in—it’s about real, measurable agility. Modular architectures allow organizations to adjust components independently as requirements change. CTOs are intentionally placing workloads where they perform best—cloud for global scale, on-prem or colocation for heavy AI training, and edge for low-latency inference—and treating each as part of a unified, purpose-driven infrastructure strategy.
This pattern holds true beyond just AI.
In cyber resilience, what matters when a ransomware event hits isn’t whether you bought every tool from one vendor; it’s the speed and predictability of recovery (which specialized, resilient storage does more to accelerate than bundled dashboards)
In cloud native application development, developers value predictable performance, clear pricing, and flexibility over being locked into a single ecosystem.
In media and entertainment, workflows often span regions, partners, and technologies—moving petabytes of creative content, generating AI media assets, and orchestrating distributed rendering jobs. A modular approach enables teams from all sides of the business (creative and technical) to optimize for performance without constraint.
These use cases share common themes: avoid lock-in, preserve optionality, control costs, and maintain performance predictability. These align with broader industry sentiment that hybrid and composable architectures deliver greater agility and resilience in the face of evolving requirements.
Depth over breadth: A focused infrastructure philosophy
When vendors expand aggressively into adjacent domains—analytics, governance, AI tooling—they risk breadth at the expense of depth. In fast-moving markets, “jack-of-all-trades” platforms often become “master-of-none.” Best-of-breed doesn’t mean disjointed; it means each layer is optimized for its purpose and integrated intelligently.
That’s the philosophy behind how we’ve evolved our own infrastructure. When Backblaze first launched our object storage service, we highlighted performance, transparency, and cost efficiency. As AI and high-throughput workloads accelerated, customers began using us as neutral infrastructure for staging, throughput, and data mobility between clouds. We leaned deeper into storage—high-throughput tiers, bandwidth guarantees, lifecycle tools—but intentionally stopped short of climbing higher up the application or analytics stack.
We draw a line at storage not because adjacent layers lack value, but because storage is foundational. AI differentiation, application logic, and workflow intelligence happen above the infrastructure layer. Customers need owned, interoperable workflows that can plug into any compute or AI platform without being co-opted by a monolithic ecosystem.
Modular infrastructure as a strategic backbone
Best-of-breed doesn’t mean fragmentation; it means focus with composability. The future of enterprise infrastructure isn’t about building the tallest platform—it’s about building the strongest foundation that supports innovation across many dimensions.
Across industries, infrastructure leaders are embracing workload placement strategies and hybrid models to optimize for cost, governance, and performance. In AI, this means hybrid cloud and on-prem strategies where appropriate; in traditional application and file storage, it means interoperable, resilient services; and in media workflows, it means performant pipelines unencumbered by monolithic stack limitations.
The companies that win in this era won’t be those who own every layer. They’ll be those who enable others to build faster, iterate often, and adapt without constraint.
Ransomware and other disruptive attacks rarely succeed because of a single catastrophic failure. More often, they succeed because a system was designed for availability and scale, but not for persistent, adaptive adversaries testing for weak points from the outside.
For infrastructure and architecture leaders, that creates a practical challenge: how do you build systems that remain performant, cost-efficient, and operable while also standing up to attackers who are probing your environment for opportunities through traffic abuse, credential attacks, vulnerability exploitation, and social engineering?
The answer is not a single tool or framework. It is an architectural mindset: assume adversaries exist, assume controls will be tested, and design systems that continue operating safely under pressure.
Security starts with architecture, not alerts
One of the most common mistakes organizations make is treating security as something layered onto infrastructure after it is built. In practice, resilience comes from decisions made much earlier:
How traffic is handled under stress.
How systems and services are segmented.
How identity and access are enforced.
How quickly vulnerabilities are surfaced and validated.
How failure is contained when something goes wrong.
This is what separates reactive security from resilient architecture. The strongest environments are not the ones with the most dashboards; they are the ones built so that no single weakness can easily cascade into a broader incident.
Designing the perimeter to buy time, not perfection
Even in a world shaped by zero trust, the perimeter still matters, especially for availability.
Large-scale traffic floods, automated scanning, and API abuse are often the opening move. These events may not be the full attack, but they can create noise, consume resources, and open the door for more targeted follow-on activity. Infrastructure teams need defenses that can:
Absorb unexpected traffic without cascading failures
Distinguish abusive patterns from legitimate use
Prevent noisy attacks from turning into operational incidents
These defenses can never provide perfect prevention; cybercriminals can attack with too much sophistication and velocity. Rather, the goal is resilience. Good perimeter design buys time, preserves service availability, and prevents external pressure from becoming internal disruption.
Modern environments change too quickly for occasional reviews to be enough.
Attackers do not work on quarterly schedules, and neither should defensive programs. A stronger model is continuous vulnerability discovery: using multiple signals to understand what is exposed, what is exploitable, and what actually matters.
That can include a mix of:
Threat intelligence on active exploitation trends
External research programs such as bug bounties
Regular penetration testing
Internal testing and automated vulnerability scanning
Each of these presents different types of risk. Together, they reduce blind spots and help teams prioritize fixes based on real-world likelihood and impact, not just severity scores on paper.
Limiting blast radius is an architectural responsibility
A useful security question is not only “How do we stop every attack?” but also “What happens if one control fails?”
That shift changes how teams think about system design. It places greater emphasis on:
Hardening critical systems
Enforcing strict access controls
Separating environments and services
Reducing unnecessary trust relationships
Containing failure before it spreads
This is where architecture has an outsized role. Detection matters, but containment matters just as much. Systems built with clear boundaries are easier to defend and easier to recover operationally when incidents happen.
Identity is part of infrastructure
Many attacks do not begin with sophisticated exploits. They begin with compromised credentials, reused passwords, phishing, or other attempts to gain access through people rather than code.
That is why identity should be treated as a core infrastructure layer, not a separate administrative concern.
Strong identity practices often include:
Long, high-entropy passwords
Multi-factor authentication
Checks for compromised credentials
Clear access policies tied to real job needs
These controls reflect a simple truth: humans are part of the system. Security controls need to be strong enough to resist abuse and usable enough to work at scale.
Security as a system, not a checklist
No single control creates resilience on its own.
What matters is how controls reinforce one another: how traffic protections support availability, how vulnerability discovery informs remediation, how segmentation reduces impact, and how identity controls protect critical paths.
For infrastructure and architecture leaders, the takeaway is straightforward: the most resilient systems are not built on assumptions of safety. They are built on the expectation that adversaries will look for openings and that defenses need to hold up under real pressure.
That is why security works best as an architectural decision, not just an operational one.
A practical Backblaze perspective
At Backblaze, this is the lens we use when thinking about protection against bad actors: not as a single feature or isolated control, but as a layered systems problem that spans network protections, vulnerability discovery, access controls, and operational resilience. The important point is not any one safeguard in isolation. It is the way those safeguards work together so that a single weakness is less likely to become a customer-impacting event.
Download the ebook on building an affordable, resilient disaster recovery strategy that matters when ransomware strikes.
When evaluating cloud providers, cost is often the most visible factor—but in enterprise IT, information security (InfoSec), and compliance, securityis always the first (and likely most important) concern. As a technology leader, you know that determining “acceptable” risk is a moving target, but you’re likely also regularly squeezed by budget pressures and a mandate to contribute to the company’s bottom line.
Taking a chance on providers with lower price tags might feel like too big of a risk—lower-cost providers must be sacrificing something, and all too often, that something is security. Right?
It’s a fair question, but the answer might surprise you. Today, we’re talking about how specialized cloud providers provide surprising value—and even provide security benefits—when compared with traditional, hyperscaler architectures. Let’s talk about what you need to know to evaluate a cloud provider’s security posture.
Want to hear from the experts?
Join our upcoming session to hear from Backblaze experts Troy Liljedahl, Sr. Director, Solutions Engineering, and Pat Patterson, Chief Technical Evangelist, about the knowledge and features you need to stay ahead of modern threats.
Join us to learn:
Foundational controls: Master the best practices for using encryption, Object Lock, access keys, role-based access controls, and more to build a solid defense.
Advanced threat detection: Get an exclusive look at Backblaze’s new feature, Anomaly Alerts, which helps detect irregular and potentially suspicious data access patterns.
A unified approach: Understand how to integrate these powerful features to create a strong, easy-to-manage security strategy.
How specialized cloud providers provide security benefits
In theory, cloud architecture encourages redundancy. But in practice, many companies—even those using multi-cloud strategies—tend to consolidate key services like authentication and orchestration with a single vendor. When that vendor’s services go down, it doesn’t matter that your data is replicated across three availability zones in the same data center. If you can’t log in to access it, your redundancy becomes purely theoretical. This year alone, there have been major outages that had widespread consequences from the likes of Google, IBM cloud, and others.
Specialized cloud providers and multi-cloud strategies provide inherent benefits here.
Vendor transparency: Open cloud providers publish clear, detailed practices around architecture, encryption, and compliance rather than burying them behind opaque marketing claims. This transparency allows your teams to independently validate security assurances.
Avoiding lock-in: Multi-cloud strategies ensure you’re not beholden to a single vendor’s security practices. If one provider falls short, data replication and redundancy across platforms can maintain both compliance and resilience.
Risk distribution: By spreading workloads across providers, organizations mitigate the risk of a single point of failure, outage, or vendor breach.
Compliance flexibility: Different providers may align more strongly with specific frameworks (SOC 2, HIPAA, GDPR, etc.), giving enterprises options to meet evolving regulatory demands.
This means that organizations don’t have to choose between cost efficiency and security—they can and should get both.
How to evaluate a cloud provider’s security posture
Choosing the right cloud provider isn’t just about price, features, or performance—it’s about knowing they can safeguard your data and prove it. Here are key areas to assess:
Architecture & physical security
Does the provider operate its own infrastructure or rely on generic colocation facilities?
What physical safeguards (biometrics, restricted access, surveillance) protect the data centers?
Encryption & data protection
Is data encrypted both in transit (TLS/SSL) and at rest (AES-256 or equivalent)?
Are key management options available, including customer-managed keys?
Is immutability (Object Lock or write once, read many (WORM) storage) supported for ransomware defense?
Access & identity controls
Are granular permissioning and role-based access (RBAC) controls available?
Does the provider support single sign on (SSO), multi-factor authentication (MFA), and integration with enterprise identity systems?
Can admins maintain clear audit logs of all access and changes?
Compliance & certifications
Which third-party attestations does the provider maintain (SOC 2, HIPAA, PCI-DSS, GDPR, ISO)?
Can they provide signed agreements (such as Business Associate Agreements (BAAs)) as needed for regulated industries?
Resilience & multi-cloud strategy
Do they offer replication across regions or the ability to integrate into a multi-cloud strategy?
How quickly can you move workloads or data out if you need to change vendors or access data in case of emergency?
By using this evaluation framework, IT leaders can look past marketing promises and price tags, focusing on verifiable controls and independent certifications.
The hyperscaler tax for cloud security
Many enterprises assume that higher cloud storage costs from hyperscalers like AWS, Azure, or Google Cloud translate directly into better security. In reality, much of that premium is a “hyperscaler tax” driven by complex business models, bundled services, and legacy infrastructure—not inherently superior protection. Specialized cloud providers can often deliver the same enterprise-grade security controls—encryption, compliance certifications, access management—without the inflated price tag, proving that security and affordability are not mutually exclusive.
Building a better mousetrap: The innovation behind Backblaze B2
From the beginning, Backblaze has architected its storage solution to be both performant and cost-effective. And, by specializing in storage (as opposed to the myriad of solutions offered by, say, Amazon Web Services and other hyperscalers), Backblaze is able to optimize for the economics of storage and storage alone.
To help you get past the price tag and into the technical details, let’s break down the pillars of Backblaze B2 security and compliance.
Compliance? We’ve got a visual for that.
Want a quick glance on how Backblaze compares to other cloud storage providers on key security and compliance elements? Check out our comparison matrices.
Architecture and physical security: The foundation of trust
Our security starts with our physical infrastructure. Our data centers are designed for 11 nines of data durability and are staffed 24/7/365. They feature:
Best-in-class security features: Biometric security, ID checks, and multi-layered access controls.
This physical and architectural security is the bedrock of our service, and it’s backed by industry-standard certifications like SOC 2 Type 2 certification.
Data storage security: Protecting data at rest and in transit
Data security is a core tenet of our platform. From the moment your data leaves your system until it is stored on our pods, it is protected by multiple layers of encryption.
Encryption in transit: All files are transmitted to Backblaze B2 using an encrypted TLS connection.
Encryption at rest: Your data is encrypted before it is stored on disk. We offer two options for server-side encryption with 256-bit Advanced Encryption Standard (AES-256):
Server-side encryption (SSE) with Backblaze managed keys (SSE-B2): We handle the key management for you, providing seamless, built-in protection.
SSE with customer managed keys (SSE-C): For organizations with strict compliance requirements, you can manage your own keys, giving you complete control over your data’s access.
Object Lock for immutability: Our Object Lock feature provides a powerful layer of ransomware protection. Using a write-once, read-many (WORM) model, it prevents files from being modified, manipulated, or deleted for a customer-determined retention period. This is an essential tool for compliance and disaster recovery.
Cloud Replication: For businesses with high-availability or geographical redundancy requirements, Backblaze B2 supports automatic replication of data across different regions, ensuring your data is always available and safe from regional outages or other incidents.
Access management security: Granting control and ensuring accountability
Controlling who can access your data is paramount. We provide granular, enterprise-grade access management controls that give you full command over your storage:
Fine-grained API key control: Create and manage accounts, groups, and specific data access permissions with robust API key control.
Multi-factor authentication (MFA) & single sign-on (SSO): We offer multiple account authentication options, including MFA and SSO via providers like Google Workspace and Office 365, to prevent unauthorized access.
Comprehensive logging: Backblaze provides detailed logs and reports on all activities within your account, so you can maintain a clear audit trail.
Compliance: Demonstrating our commitment to best practices
Security is not just a feature; it’s a commitment that’s verified by independent third parties. Backblaze has achieved a number of security and compliance attestations, including:
SOC 2, Type 2: We have been independently audited and certified for SOC 2, Type 2 compliance, demonstrating our commitment to protecting customer data.
HIPAA: For business customers who are Covered Entities under the Health Insurance Portability and Accountability Act (HIPAA), we can provide a Business Associate Agreement (BAA) upon request.
PCI-DSS: Backblaze’s adherence to the Payment Card Industry Data Security Standard (PCI-DSS) is supported by our use of Stripe to handle card information and our internal security controls.
GDPR: We adhere to General Data Protection Regulation (GDPR) privacy policies and provide Data Processing Agreement Addendums (DPAs) for EEA/EU and UK residents.
While some competitors may also offer these certifications, Backblaze’s pricing model is built to ensure you don’t have to pay a premium for them. Our efficiencies mean that we can pass the savings directly to you without compromising on the security and compliance that your business demands.
Specialized cloud storage: Enabling enterprises to evaluate their best options
In the end, our goal is to free you from the false choice between security and affordability. The reality is that the high cost of some cloud providers is a result of their complex, multi-tiered business models—not a reflection of superior security. Backblaze’s commitment to building a focused, innovative, and transparent cloud storage solution allows us to deliver on our promise: enterprise-grade security and compliance, at a fraction of the cost.
As more organizations rely on the cloud to store critical data, the stakes around compliance and security keep rising. Regulations like GDPR and HIPAA are putting pressure on businesses to demonstrate that their data handling practices are sound, and customers increasingly want evidence—not just assurances—that their data is protected.
Every cloud provider claims to be “secure.” But as a risk owner and decision-maker, you need more than a marketing tagline. You need proof. That’s where SOC 2 Type 2 compliance comes in. At Backblaze, we don’t just meet this benchmark—we go beyond it. Unlike many cloud storage providers (CSPs) that may have only SOC 2 compliant data centers, Backblaze has also undergone the rigorous SOC 2 assessment at the company level.
What is SOC 2, and why does it matter?
SOC 2 (aka System and Organization Controls) is an assessment created by the American Institute of Certified Public Accountants (AICPA). It evaluates how service providers operate based on Trust Services Criteria:
Security
Availability
Confidentiality
Privacy
Processing integrity
Every SOC 2 assessment includes Security as the foundation, and organizations may also be evaluated against additional criteria that align with their services. Our assessment covers both Security and Availability, demonstrating that our systems are protected against unauthorized access and are resilient, reliable, and consistently accessible when you need them.
Regular penetration testing and incident response reviews.
The business impact? You can rely on us to keep your data safe and accessible—without adding unnecessary risk to your operations.
Type 1 vs. Type 2: A key distinction
There are two types of SOC 2 examinations:
Type 1 shows that a company has the right controls in place at a specific point in time.
Type 2 goes further by validating that those controls are consistently followed and effective over a defined period.
Backblaze has achieved and consistently maintained SOC 2 Type 2 compliance. That distinction matters—it means you’re not just trusting that we say the right things, but that we do the right things, day in and day out.
What SOC 2 compliance delivers
SOC 2 compliance isn’t just a checkbox exercise. It provides meaningful assurances that directly affect your business:
Risk mitigation: Independent validation that controls work as intended.
Trust and credibility: Confidence that your cloud provider takes security seriously.
Vendor due diligence: Simplifies compliance reviews for your team.
Data integrity & availability: Assurance that your data remains reliable and accessible.
In short, SOC 2 compliance reduces uncertainty—making it easier for you to move forward with cloud adoption and scale with confidence.
SOC 2 data centers vs. SOC 2 as a company
It’s important to distinguish between compliance at the data center level and compliance at the company level.
SOC 2 compliant data centers: These examinations focus on the physical facility—things like access controls, environmental monitoring, and fire suppression. Many CSPs rely on SOC 2 certified facilities.
SOC 2 compliance as a company: This examination covers the provider’s internal operations, including policies, processes, and personnel practices. It examines how the service is built, run, and maintained.
Backblaze offers both. Our data centers are SOC 2 compliant, and our company is also SOC 2 Type 2 compliant.
Think of it like a bank: Secure vaults are critical (data centers), but so are strong internal policies and trained staff (company compliance). And, of course, you want both. That’s what we call defense in depth—end-to-end assurance that reduces risk and builds trust.
Surprisingly, you’ll find that many CSPs have SOC 2 data centers, but do not hold SOC 2 compliance at the company level.
Inside the SOC 2 audit process
SOC 2 evaluations are performed by independent third-party CPA firms, which ensures the results are objective and credible. The process includes:
Scoping: Identifying which systems and processes are reviewed.
Control documentation: Recording policies and procedures.
Evidence collection: Proving that controls are in place.
Testing & evaluation: Verifying effectiveness over time.
Reporting: Delivering findings in a formal report.
At Backblaze, this isn’t a one-and-done exercise. We undergo annual audits, maintain robust monitoring, and test our systems regularly. For example:
Incident response plans, playbooks, and processes are reviewed and updated as needed.
Penetration testing, the public bug bounty program, and our vulnerability management processes are designed to proactively identify, evaluate, prioritize, and remediate potential vulnerabilities.
Each step reinforces our commitment to security and transparency—so you don’t have to take our word for it.
Policies that protect your data
Policies and processes are the backbone of an effective SOC 2 program. At Backblaze, these policies aren’t just written down; they’re embedded in how we operate every day.
Change management (Security, Availability)
Changes that impact our systems, infrastructure, or software are controlled, tested, and approved before release. This prevents unauthorized or accidental changes that could disrupt operations or compromise security. For customers, this means you can rely on a stable, reliable storage platform that won’t jeopardize your workflows.
Logging & monitoring (Security, Availability)
We log system activities, monitor access attempts, and alert on high priority security events around the clock. We have implemented features such as Anomaly Alerts to support notifying customers about unusual file upload and download patterns. Bucket Access Logs give you visibility into who accessed your data and when—adding both accountability and an audit trail for incident response.
Media handling & drive destruction (Security)
Physical media like drives are tightly controlled throughout their lifecycle. When a drive reaches end-of-life, it undergoes a secure erasure process. If it is not able to be securely erased, the device is destroyed, ensuring data is completely unrecoverable.
Environmental security (Availability)
Protecting data also means protecting the environment where it lives. Our data centers are equipped with redundant power and cooling systems, fire suppression, and environmental monitoring. Facilities are staffed 24/7/365 to respond to incidents in real time. These measures ensure uptime and business continuity—even in the face of physical disruptions like outages or natural disasters.
Each of these policies maps directly back to Trust Services Criteria, but more importantly, they translate into reduced risk, stronger reliability, and greater peace of mind for your business.
Why Backblaze stands apart
If you’re evaluating cloud storage providers, you can request a copy of our SOC 2 Type 2 report through Whistic. Backblaze currently offers 3 profiles on Whistic: Education Industry profile link, EU Customers profile link, or All Other Customers profile link. Once you have signed up, or signed in, you will be able to view or download the applicable documents and questionnaires.
Backblaze’s combination of SOC 2 compliant data centers and company-wide SOC 2 Type 2 compliance provides a higher level of assurance than many providers offer. That additional assurance is a powerful differentiator, especially for businesses in regulated industries.
And we’re not stopping here. Security isn’t static. We commit to annual assessments, continuous monitoring, and adapting to new threats as they emerge—so you can trust that your data is in good hands today, tomorrow, and beyond.
If you’ve spent any time sourcing, evaluating, or speculating about cloud services in the public sector lately, you’ve likely felt it: the arms race happening in compliance. Courting customers from schools to statehouses to national labs, more and more cloud vendors are racing to pin the next security badge to their lapel—GovRAMP (formerly known as StateRAMP), TX-RAMP, FedRAMP, SOC 2, and on and on.
And while it might feel like a compliance bingo card, there’s real strategy and real consequences behind this sprint. At the heart of it all is the SLED market (state and local government, and education)—a sprawling patchwork of institutions tasked with safeguarding citizen data and taxpayer trust, all while operating with limited resources and infrastructure budgets.
Let’s talk about why this compliance arms race exists, what it means for buyers and vendors alike, and how we at Backblaze are choosing to compete not just with checkboxes, but with character.
Why does SLED even need unified standards?
Public sector IT has long been a security quilt. Some agencies stitched up with advanced defenses, others more… threadbare. While some may have advanced security tooling, a K–12 school district might still be running on legacy systems and duct tape. Yet both manage data that’s increasingly digital, distributed, and vulnerable.
The result? Inconsistent practices and rising risks. Enter: GovRAMP.
What is GovRAMP?
Short for Government Risk and Authorization Management Program, GovRAMP was customized to standardize cloud security for state and local agencies. It’s actually based on the same set of controls for FedRAMP—controls derived from the National Institute of Standards and Technology (NIST) SP 800-53, a catalog of controls for organizations to manage cybersecurity and privacy risk. GovRAMP ensures that even the smallest public institutions can procure secure IT solutions without reinventing the wheel every time.
GovRAMP was originally launched as StateRAMP, but has since grown beyond state lines, evolving into a broader framework adopted by local governments and school systems. Today, it’s a rigorous, independent audit program that holds vendors to a high set of security controls. Translation: If a vendor is GovRAMP-authorized, they’re playing in the big leagues of cloud security.
The alphabet soup of compliance: TX-RAMP, GovRAMP, FedRAMP
If you’re in Texas, you’re probably familiar with TX-RAMP, the state’s specific compliance framework. The good news? GovRAMP and TX-RAMP are closely aligned. At Backblaze, our GovRAMP Progressing Snapshot status qualifies us for TX-RAMP Provisional Authorization as well—one less hurdle for Texas agencies seeking secure, scalable cloud storage.
As for FedRAMP, it remains the gold standard for federal data, but for the vast majority of public sector orgs, including most SLED agencies, it’s simply unnecessary.
How GovRAMP streamlines cloud sourcing
Here’s where the compliance arms race actually makes things easier: Once a vendor is authorized through GovRAMP, SLED buyers can trust that the solution meets certain security standards, saving months of one-off vetting, paperwork, and duplicated audits. In a procurement environment plagued by inefficiency, that’s no small thing.
Especially now, as budgets tighten and AI-driven everything drives demand for flexible infrastructure, reducing sourcing friction matters more than ever.
Going beyond checklists: What buyers should really look for
Checkboxes alone don’t guarantee real-world resilience. Compliance can become its own form of security theater. It looks good on paper but falls short in practice. That’s why buyers should dig deeper.
Look for vendors who not only pass audits but live and breathe their controls. That means going beyond annual assessments and embracing security as a continuous, integrated discipline. The best partners are transparent, proactive, and thoughtful about risk—not just checking boxes, but building real-world resilience. Here are a few signs to look for:
Continuous monitoring and internal audits: They treat compliance as an ongoing process, not a once-a-year scramble.
Clear, accessible documentation: Security policies, certifications, and standardized independent attestations are available (under NDA if needed), not locked in a black box.
Transparent data practices: They’re upfront about where your data lives, who can access it, and what happens in the event of an incident.
Responsive support: You can communicate with real people who understand your risk profile—not just surface-level answers or automated replies.
Affordable recoveries: They don’t make recovering your data prohibitively expensive. Look at their egress policies and price out what it would actually cost to retrieve your data.
When you’re responsible for protecting sensitive data, it’s not enough to be compliant. You need a partner who’s disciplined, trustworthy, and invested in your resilience.
The Backblaze approach: Rigor, transparency, and trust
Pursuing authorizations like GovRAMP and TX-RAMP isn’t easy, but it’s the right thing to do and we’re committed to the process. We believe public sector buyers deserve cloud partners who understand their constraints, meet them where they are, and still bring best-in-class solutions to the table.
But more than that, we’re not stopping at frameworks. Compliance is a floor, not a ceiling. We’ve built our platform on decades of operational rigor and security discipline—not to impress auditors, but to earn your trust. And we’ve structured our products to enable security best practices, not hinder them, including 3x free egress for disaster recovery.
So yes, we’re proudly in the compliance race. But we’re not just chasing badges. We’re building something secure, sustainable, and ready for whatever comes next.
Want to learn more about our GovRAMP journey or how Backblaze supports public sector cloud transformation? Reach out to our Sales team.
Disaster recovery (DR) is a top-line priority for enterprise organizations facing increasingly complex threats—sophisticated ransomware attacks, widespread cloud outages, and regulatory risks. The ability to recover quickly and maintain business continuity isn’t just a technical necessity—it’s a competitive imperative.
Today, I’m breaking down foundational strategies for enterprise DR readiness. You’ll find practical guidance on infrastructure design, site strategy, backup best practices, and more to help you take immediate action.
Get the full guide
Our “Essential Guide to Disaster Recovery Planning” offers a comprehensive framework for designing a DR plan that protects your business across multiple threat vectors.
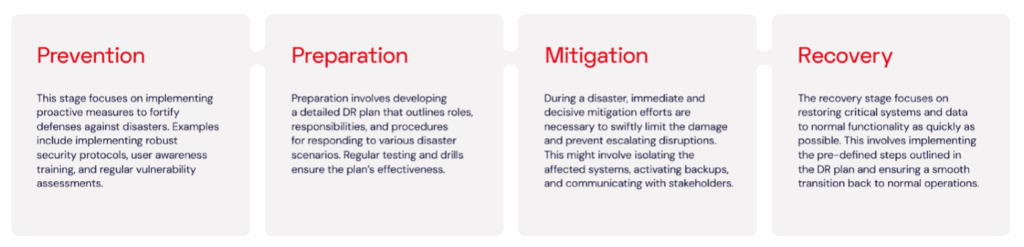
Comprehensive DR requires a multi-tiered approach. Your DR strategy should encompass four critical stages: prevention, preparation, mitigation, and recovery.
Choose the right infrastructure: Beyond legacy limitations
Many enterprises still rely on legacy storage technologies like tape, which create delays in restoration and introduce hardware failure risks. Shifting to cloud-first infrastructure reduces these vulnerabilities while unlocking scalability and location diversity. It also supports immutability features—critical for ransomware resilience—and simplifies compliance with evolving regulations.
Cloud platforms also unlock new options for data governance and sovereignty. Enterprises operating across regions or industries governed by strict data residency laws can configure cloud storage to maintain compliance while reducing operational overhead.
As enterprise backup and archive needs grow, it becomes vital to distinguish between long-term cold storage and actively accessible data. With clear infrastructure planning, organizations can streamline operations and ensure faster recovery without overspending on high-performance systems for archival workloads.
What is Object Lock?
Object Lock is the feature in cloud platforms that enables immutability. With immutability, your data cannot be changed, deleted, or encrypted. This is the ultimate protection against ransomware.
DR site temperatures: Hot, warm, or cold?
Depending on your recovery time objective (RTO), different types of recovery sites offer different benefits:
Hot sites: Fully mirrored and ready for instant failover—great for mission-critical apps but expensive.
Warm sites: Pre-configured but not fully live—strike a balance between cost and speed.
Cold sites: Infrastructure is ready but requires manual configuration—most affordable, but slowest to recover.
Enterprises evaluating DR readiness should consider whether their current configuration meets their recovery time goals—and whether they’re optimizing for the right workloads. Comparing hot, warm, and cold site models can help strike the right balance between performance and budget.
Build vs. buy vs. cloud: Finding the right fit
Selecting a DR site is fundamental to your strategy. There are four main approaches to establishing a DR site: building your own, buying services from a co-location provider, buying public cloud storage, or leveraging a disaster recovery as a service (DRaaS) solution. Each approach offers distinct advantages and drawbacks.
Building an on-premises DR site
Pros: It provides complete control over the DR environment, offering greater customization and security.
Cons: Significant upfront investment in hardware, software, and facility infrastructure and management. Requires ongoing maintenance and staffing costs. Limited scalability to accommodate future growth.
Buying co-located DR storage
Pros: It offers a cost-effective alternative to building your own site. Co-location providers manage aspects of the physical infrastructure, reducing your IT team’s workload.
Cons: Less control over the environment compared to an on-premises solution. May require additional investment for network connectivity and configuration. Potential vendor lock-in with specific co-location providers.
Buying public cloud-based DR storage
Pros: Highly scalable and cost-effective. CSPs manage the physical infrastructure, reducing your IT team’s workload. Features like Object Lock help address security concerns versus on-premises storage.
Cons: Retrieving large volumes of data may be slow due to bandwidth constraints.
Buying disaster recovery as a service (DRaaS)
Pros: Highly scalable and cost-effective solution. Eliminates the need for upfront infrastructure investment. DRaaS providers manage the entire DR environment and provide technical support, freeing up your IT staff.
Cons: Reliance on a third-party provider for critical data and infrastructure. Potential concerns over network latency and vendor lock-in. Security considerations require a careful evaluation of the cloud provider’s practices.
Backup vs. replication: Know the difference
Replication copies data in real-time, but that also means it can copy infected or corrupted data. Backups, on the other hand, offer point-in-time recoveries so you can restore data even after a ransomware attack.
The optimal approach to DR depends on your specific needs.
For frequently accessed data requiring near-instantaneous recovery, consider a combination of hot site methodology and real-time data replication. This offers the fastest failover, but can come at a higher cost.
For critical data with acceptable downtime, a warm site with replicated immutable backups at a secondary location (either on-premises or in the cloud) provides a good balance between cost and recovery time. While requiring some manual intervention, it offers protection against malware replicating to the DR site.
For less critical data or archival purposes, cold storage with periodic backups is a cost-effective option. Backups offer a historical record and are less susceptible to malware infection compared to replicated data, particularly if Object Lock is enabled for immutability.
SaaS outages are a threat you can’t ignore
Although built for high availability, SaaS apps don’t guarantee protection against data loss. Tools like Microsoft 365 and Google Workspace are built for uptime, not recovery. Misconfigurations, insider threats, and accidental deletions remain common risks. Enterprises should take control of their own retention policies with dedicated SaaS backup strategies, including regular point-in-time snapshots and recovery testing.
Additionally, planning for SaaS outages should include identifying local alternatives for core business functions. Can teams temporarily revert to offline workflows? Are key contacts available outside of email or Slack? Defining fallback protocols ensures that productivity doesn’t grind to a halt even if your primary tools go dark.
Assembling your incident response team
The incident response team (IRT) is the backbone of your DR response and is responsible for leading the recovery efforts during a disaster. Here’s a breakdown of possible key IRT roles:
Incident commander: Oversees the entire incident response process, making critical decisions and delegating tasks to team members.
Technical lead: Provides technical expertise, directing recovery efforts for IT infrastructure and data restoration.
Communications lead: Handles external and internal communication, ensuring timely updates for stakeholders and mitigating potential reputational damage.
Documentation lead: Maintains the DR runbook, ensuring its accuracy and updating it with post-incident findings.
Legal counsel: Provides legal guidance and ensures compliance with relevant regulations during the response and recovery process.
Objectives, priorities, and KPIs: The compass of your DR strategy
A robust DR strategy starts with clearly defined objectives and priorities. These guide your approach and decision-making during a disaster recovery event. Your strategy should prioritize rapid recovery of critical systems and applications to minimize operational downtime and resume normal functions swiftly.
Prioritization: Not all data (or systems) are created equal
Prioritizing your critical business applications depends on a deep understanding of your business. Collaborate with internal partners to identify critical business applications that are essential for ongoing operations. Not all applications require immediate restoration. Prioritize systems based on their impact on core business functions.
Documentation is key
A popular mantra for DR specialists is “Test the plan; don’t plan the test.” Your DR plans must be clearly documented as working recipes for application and data recovery, including dependencies and prerequisites. Document the recovery procedures for each critical application, outlining the steps required to bring them back online. This ensures your IT team can efficiently restore essential services during a disaster.
Primary DR objectives
Minimize data loss: The primary objective is to minimize data loss through regular backups and secure storage practices.
Ensure business continuity: The DR plan aims to rapidly recover operation of critical functions during a disaster, minimizing disruption to the business goals.
Optimize costs: Application and data recovery needs to balance speed and costs to ensure recoverability without unnecessarily increasing IT spending.
Compliance considerations
Compliance regulations might influence your DR priorities. Understand any industry-specific regulations or data privacy laws that might dictate specific data protection and recovery timeframes.
Collaborative RTO and RPO setting
Working with internal partners to set RTOs and RPOs ensures alignment across the organization.
Recovery Time Objective (RTO) defines the acceptable timeframe for restoring critical applications to a functional state.
The Recovery Point Objective (RPO) defines the maximum tolerable amount of data loss acceptable in the event of a disaster.
Stakeholders need to understand the realistic trade-offs involved in setting RTOs and RPOs, balancing the need for quick recovery with resource and cost limitations. Achieving extremely short RTOs, such as recovery within minutes, might require substantial investments in advanced infrastructure, redundant systems, and skilled personnel. Setting achievable RTOs and RPOs that effectively balance the need for swift recovery with the financial limitations of the organization requires open communication and collaboration.
Restore vs. recovery: Understanding the nuances
It’s important to distinguish between data restoration and system recovery. Data restoration specifically involves retrieving data from backups. On the other hand, system recovery encompasses the comprehensive restoration of data, applications, configurations, and user accounts to fully restore system functionality.
Your RTOs should focus on the time it takes to bring an application to a usable state, not just the time to recover the data.
Setting expectations
Employees might have unrealistic expectations regarding recovery times during a disaster. Educate the organization on the DR process and the inherent complexities involved.
Developing measurable KPIs
Tracking your progress Key performance indicators (KPIs) are your guiding metric for measuring the effectiveness of your DR strategy. Here are some key DR-related KPIs to consider:
RTO achievement rate: Tracks the percentage of times critical applications are restored within the established RTO.
RPO achievement rate: Measures the percentage of data recovered that meets the defined RPO.
DR plan testing frequency: Monitors how often the DR plan is tested to ensure its effectiveness.
Mean time to recovery (MTTR): Tracks the average time taken to recover critical applications after a disaster.
Data loss rate: Measures the amount of data lost during a disaster compared to the established RPO.
These KPIs provide valuable insights into your DR preparedness and help identify areas for improvement.
Strengthen your RTO and RPO goals with the cloud
Recovery time objectives (RTOs) and recovery point objectives (RPOs) are the backbone of any DR plan. Yet many organizations set unrealistic targets without fully accounting for infrastructure, bandwidth, or cost constraints.
Establishing tiers of RTO and RPO based on data type or application criticality helps organizations avoid overengineering. Not every workload needs sub-hour recovery—archived legal files or marketing collateral may tolerate 24+ hour RTOs. Grouping systems into priority tiers ensures efficient use of budget and infrastructure while keeping SLAs aligned to business risk.
Improving these metrics often comes down to using the right storage architecture. By offloading backup workloads to cost-effective cloud storage with integrated immutability and replication, enterprises can improve RTO and RPO without the overhead of traditional DR environments.
A proactive, iterative approach
A DR plan isn’t a one-time project—it’s a living process that should evolve with the business. Every test, every incident, and every infrastructure change is an opportunity to improve.
Strong DR programs rely on frequent validation, leadership alignment, role clarity, and avoiding common missteps. As IT leaders face new threats and shifting architectures, resiliency comes from readiness—not just recovery.
Testing is everything
Even the most comprehensive DR plans can falter if they aren’t regularly validated. Testing ensures that backup data is restorable, that systems behave as expected under stress, and that team roles are clearly understood.
Testing also gives stakeholders across departments a shared language for discussing DR. Finance understands the cost implications of downtime, Legal sees the impact of non-compliance, and Security can stress-test assumptions about containment and escalation. When testing is multidisciplinary, recovery isn’t just possible—it’s predictable.
Organizations that incorporate routine DR drills and testing into their operations tend to recover faster and more confidently. Effective exercises can include walk-throughs, tabletop simulations, and full-scale failover tests. The goal isn’t just compliance—it’s ensuring the organization can execute when it matters most.
Cost transparency and budgeting for DR
Budget uncertainty often limits the scope and effectiveness of DR plans. Legacy vendors may impose hidden fees for egress, API operations, or early deletion, making it difficult to forecast the total cost of a recovery event. Cloud-native solutions with transparent pricing models allow IT and finance teams to plan confidently.
Establishing a clear TCO framework—including hardware, licensing, testing, and human resources—can help justify DR investments and avoid budget shortfalls when they matter most. DR isn’t just insurance—it’s a measurable part of digital operational excellence.
Final thoughts
Disaster recovery isn’t optional—it’s essential. With threats ranging from cyberattacks to cloud outages, every organization needs a plan that’s tested, documented, and designed for rapid recovery.
Backblaze B2 helps you implement affordable, scalable, and secure DR strategies with:
Immutable backups
Flexible recovery options
Transparent pricing (no egress fees)
Seamless integrations with backup tools like Veeam, MSP360, and more
Security teams are under constant pressure to stay ahead of increasingly sophisticated threats while enabling fast, reliable access to data across the business. Whether you’re protecting media assets, safeguarding backups, or supporting a global development workflow, your cloud storage needs to do more than store data—it needs to actively support your security posture.
To make that easier, we’ve launched a new set of enterprise-grade security features for Backblaze B2 Cloud Storage. These updates are designed to help organizations detect unusual activity faster, manage access more precisely, and strengthen visibility across their storage environments—all without added complexity or hidden costs.
These new tools build on the security foundations you already count on: Object Lock for ransomware protection, SOC-2 compliance, encryption, 3x free egress for disaster recovery, and more.
Here’s a look at what’s new and how it helps.
Smarter protection with Anomaly Alerts (Now in private preview)
Anomaly Alerts are your new AI-powered watchdog. This feature analyzes usage patterns in your B2 Cloud Storage buckets to detect potential red flags—like spikes in downloads or uploads beyond the baseline—that could signal a breach or exfiltration attempt.
If your team wants early access to this feature, drop us a line at [email protected] to join the private preview.
New enterprise web console & role-based access controls (Now in private preview)
Managing cloud storage across large teams just got a whole lot easier. We introduced a brand-new enterprise web console built for scalability and control. Combined with robust role-based access controls (RBAC), IT and security teams can now better align with zero-trust policies by enforcing the principle of least privilege across their organizations.
This console simplifies storage administration at scale—whether you’re managing terabytes or petabytes.
Get an expert introduction to the enterprise web console.
If you’re a Backblaze customer with a committed contract, reach out to your Customer Success Manager (CSM) to see if you’re eligible to participate. Not sure who your CSM is? Email [email protected] for help.
Full visibility with Bucket Access Logs (Now generally available)
Need to know who touched what and when? Bucket Access Logs are now generally available, providing a detailed audit trail of every action in your B2 buckets—uploads, downloads, deletions, and more.
Learn more about querying Bucket Access Logs in this webinar.
They’re fully S3-compatible and configurable through both the Backblaze B2 web UI and API, supporting:
Security audits
Usage tracking
Forensics and threat investigation
Real-time Event Notifications
Time matters when it comes to spotting and stopping threats. With Event Notifications, you can get real-time alerts on changes to your bucket contents—think object creations, deletions, or modifications—so your team can jump into action immediately.
This is especially valuable for compliance teams, incident response workflows, or any operations team who wants tighter control over their cloud perimeter.
Watch our hands-on Event Notifications demo to learn more about how to streamline cloud storage management.
Multi-Bucket and Scalable Application Keys
Security and scalability should go hand in hand. With Multi-Bucket Application Keys, you can now create access keys that cover specific groups of buckets, giving you more flexibility without going full wildcard. This enhancement provides more granular control over bucket access, contributing to a reduced attack surface.
And, with Scalable Application Keys, you can generate up to 10,000 short-lived keys per minute. This capability enhances security by limiting the exposure window of individual keys, thus reducing the attack surface for endpoint-generated content and high-volume data operations.
Custom Upload Timestamps
Custom Upload Timestamps allow you to specify when an object was originally created or uploaded. This is a critical feature for:
Regulatory compliance
Accurate version tracking
Legal and audit requirements
Built for a Secure, Open Cloud
Security isn’t a one-time add-on, it’s an ongoing promise. As enterprises scale and integrate cloud storage into more parts of their workflow—from backup and archiving to AI pipelines—they need solutions that support open cloud strategies without compromising their data.
This update is another step forward in our mission to provide developers, IT teams, and enterprises with cloud storage that’s secure by design, simple to use, and affordable at scale. Ready to get started with Backblaze B2? Contact our Sales team today.
Your disaster recovery (DR) plan is only as strong as your last test. Yet, many enterprises treat DR like a fire extinguisher—useful in theory, but rarely checked. Regular backup testing and disaster recovery drills are essential to ensure your plan works when it counts.
Let’s break down how to test your DR plan effectively and build a framework for continuous improvement.
Step 1: Building a disaster recovery testing framework
Your DR plan isn’t complete until it includes a clear, repeatable testing schedule. Here’s how to structure it:
Testing frequency: Establish a regular testing schedule. The optimal frequency depends on your company’s size and risk profile. A minimum of annual testing is recommended, with more frequent testing (every three-six months) beneficial for larger enterprises.
Testing types: Incorporate various testing methodologies into your plan. This might include:
Tabletop exercises: Simulate disaster scenarios through facilitated discussions, allowing your team to identify communication gaps and areas for improvement in the DR plan.
Walk-throughs: Step through specific recovery procedures outlined in the plan with your incident response team, ensuring team members understand their roles and responsibilities.
Limited scope DR drills: Simulate a disaster scenario with a specific system or application outage, testing recovery procedures for that particular environment.
Full-scale DR drills: Conduct comprehensive tests that simulate a full-blown disaster, involving all critical systems, applications, and personnel.
By rotating through these disaster recovery testing approaches, you’ll catch vulnerabilities before a real crisis does.
Step 2: Involve the right people (not just IT)
A solid DR plan isn’t just an IT function, it’s a team sport. Bring in key personnel from various departments (IT, legal, finance, etc.) to review your DR plan. You might discover potential oversights or areas for improvement that you may have missed with their diverse perspectives.
Step 3: Practice makes prepared
Regularly conduct DR drills and exercises to put your plan into action. DR drills should feel real. That means:
Involving your team. These exercises should involve all members of your IRT, including IT specialists, communication experts, and management representatives, simulating real-world response scenarios and fostering teamwork within the team.
Learning from every test. The primary objective of testing is to identify weaknesses and improve your DR plan. Track everything: timing, response quality, communication breakdowns.
Conducting a retrospective. Use your DR exercises and drills to analyze successes and failures, identify areas for improvement in the DR plan and update your plan based on the lessons learned.
Encourage open discussion and feedback from all participants, including the IRT and potentially impacted stakeholders.
Identify areas where the plan fell short or where communication could be improved.
Apply these insights to fortify your DR plan and improve your company’s overall disaster preparedness.
Step 4: Make the plan accessible
Ensure your DR plan is readily accessible to your IRT members, even during a disaster. Consider storing it in a secure, cloud-based location accessible from various devices and internet connections. Ensure you can access your plan even if your primary environment is down.
Step 5: Leverage the cloud for DR testing
Consider cloud-based solutions for DR testing and recovery. This eliminates the need for ongoing infrastructure investment dedicated solely to testing purposes. Leveraging tools like cloud storage and virtualized infrastructure services provide flexible, affordable options.
Here are some key benefits of cloud-based DR testing:
Cost-effectiveness: Cloud platforms offer on-demand resources, eliminating the need for dedicated infrastructure and associated costs.
Scalability: Cloud resources can be easily scaled up or down to meet your specific testing needs.
Repeatability: Cloud environments allow for replicating test scenarios consistently, facilitating effective training and process improvement.
Final thoughts: Test, Learn, Refine, Repeat
Disaster recovery isn’t a one-and-done process. Every test is a chance to learn, refine, and prepare better for the next incident. Businesses that test regularly not only reduce downtime—they build trust with their teams, customers, and stakeholders.
Under pressure to do more with less? (Who isn’t, right?)
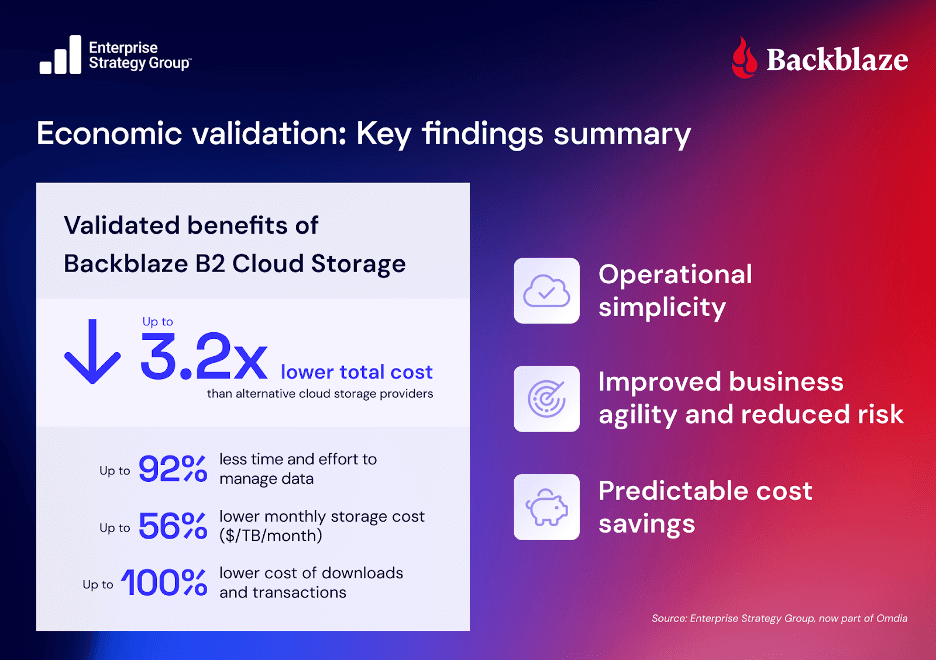
Whether you’re an IT leader or a startup founder, the last thing you want to do is waste time and money wrestling with expensive, overcomplicated cloud storage. According to a new report from Informa TechTarget’s Enterprise Strategy Group (ESG), you don’t have to. Backblaze B2 Cloud Storage delivers:
Up to 3.2x lower total cost of ownership (TCO)
Up to 56% lower monthly storage costs
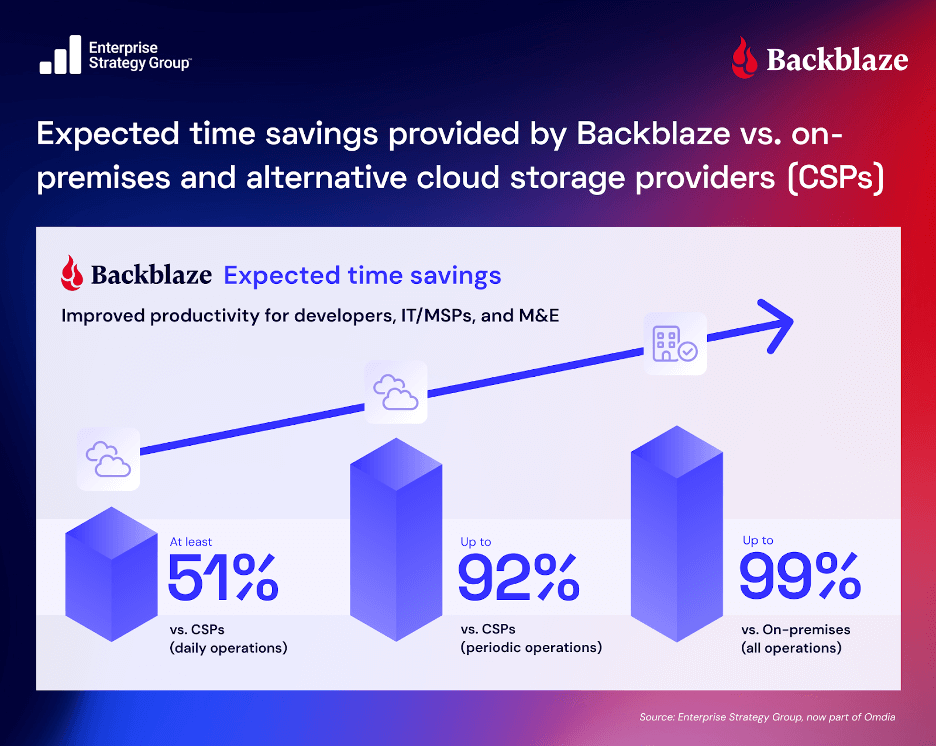
Up to 92% less time and effort to manage data
Up to 100% lower download and transaction costs
Up to 91% savings on cloud to cloud (C2C) migration costs
Economic validation: Motivation, results, and methodology
The independent analysis confirms what many Backblaze B2 users already know: Our cloud storage platform is more affordable and easier to manage compared to legacy cloud providers like AWS, Google Cloud Platform, and Azure.
To develop these findings, the ESG analysts talked to customers. They validated use cases. They used our product and verified the accuracy of our listed pricing and cost calculator. And then, they took those results along with the knowledge they’ve gathered over decades of experience to quantify the benefits that organizations can expect by using the Backblaze B2 Cloud Storage platform.
Powerful storage, real savings
The ESG report highlights how Backblaze’s predictable pricing—including at least 3x free egress, if not totally free egress in many cases—can help businesses skip the painful math of legacy storage and start getting more value out of their data. Whether you’re hosting content, training AI models, backing up critical data, or building applications, B2 Cloud Storage gives you freedom without vendor lock-in.
It’s not just about saving money—it’s about reclaiming time and resources to focus on innovation.
If you’re responsible for managing cloud storage across a fast-growing company, you know the drill: more teams, more data, more buckets—and way more complexity. That’s why we’re launching a new enterprise web console, now entering private preview.
Built for scale, security, and simplicity, the new console gives you:
Centralized control over your organization’s cloud storage.
The ability to add multiple admins who each have their own credentials.
More flexibility in bucket creation, including the ability to create buckets in any region.
Built-in zero-trust security features like mandatory MFA and SSO support.
Whether you’re wrangling storage across departments or delivering managed services to clients, this is the command center that helps you move faster, stay secure, and keep everything organized. Because managing cloud storage shouldn’t be harder than using it.
What’s new in the enterprise web console?
The new web console gives IT admins and managed service providers (MSPs) a clean, central hub for managing B2 Cloud Storage deployments—whether you’ve got a few buckets or a few thousand. Here’s what’s under the hood:
Role-based access controls (RBAC): Assign authorized admin users and utilize a resource group architecture so people only access what they need. Great for zero trust—even better for peace of mind.
Mandatory MFA: Because “security optional” isn’t really an option anymore.
SSO and SCIM support: Manage your user base automatically and at scale.
We also revamped the user interface so it’s faster to navigate, easier on the eyes, and just generally gets out of your way.
Storage where you need it
With this update, you’ll be able to create and manage B2 Buckets in any available region. That unlocks a few big wins:
Ensuring data redundancy and disaster recovery through geographically distributed backup copies.
Optimizing application performance for global users by reducing data access latency.
Compliance with data residency rules.
Ready to get started?
We’re rolling out the enterprise console in private preview starting soon. If you’re a Backblaze customer with a committed contract, reach out to your Customer Success Manager to see if you’re eligible. Not sure who your CSM is? Email [email protected] for help.
General availability is coming later this year. Stay tuned—we’ll keep shipping.
Creating clear goals is inevitably part of any business strategy. You’ve likely heard of the acronym SMART—specific, measurable, actionable, realistic, and time-bound—when it comes to goal setting. As a business leader in information technology or a related business unit, you’re responsible for developing sound goals for business technology, data protection, and disaster recovery.
Two key metrics that feed into those strategies are your recovery time objective (RTO) and recovery point objective (RPO). Like all the other goals your business sets, the RTO and RPO should also be SMART goals.
So, how can you set meaningful RTO and RPO objectives for your business? And how can the cloud help you achieve or improve on those objectives? Today I’ll talk about how to smarten up these objectives to lead to better business continuity (BC) and a more effective disaster recovery (DR) plan.
The Essential Guide to Disaster Recovery Planning
Read more about how to build a disaster recovery plan for your organization.
Why do RTO and RPO matter?
RTO and RPO are two fundamental inputs to a comprehensive disaster recovery plan. They also very much guide how you’ll structure your backup strategy and engineer your backup architecture.
RTO is a business metric that states the maximum length of time a business can tolerate for recovery. It’s important to note the difference between recovery and restoration of data here. Restoring data is just one part of a recovery.
Recovery means systems are back up and running—fully functional—with users (employees, customers, etc.) able to utilize them in the same manner as before the data incident occurred.
RPO measures the maximum amount of data a company can afford to lose (or is willing to lose), measured in units of time. For instance, an RPO of 12 hours means that the company can accept the risk (financial risk, risk to the brand, etc.) of having lost 12 hours worth of data. So, if you run backups every 11 hours, you will be able to meet your RPO.
How to set RTO and RPO
Creating these objectives is a business decision—not an IT decision. If you’re an IT leader, your job is to work with your internal stakeholders to fully understand the business and the criticality of various applications and services in order to help define the RTO and RPO.
Put another way: The decision about what standard to meet is a shared responsibility. And those standards (recovery time, file durability, etc.) are the targets that IT and infrastructure providers teams must meet.
RTO and RPO may be different from one system to another. Some applications are more important than others.
Keep in mind that it’s likely that department heads will all say their services are the most important to immediately recover. But if everything is deemed critical, then nothing is.
Discuss how data loss and time to recovery impact the business in quantifiable details—revenue lost, number of customers affected, etc.—in order to truly prioritize systems and set appropriate RTOs and RPOs.
Making your RTOs and RPOs SMART
Remember that your objectives should be SMART:
Specific: Think through how granular your RTOs and RPOs should be. In addition to different RTOs and RPOs per application, you may also need different RTOs and RPOs per scenario. For example, the RTO for a ransomware attack is much different than that for hardware failure.
Measurable: One good way of measuring the efficacy of your RTOs and RPOs is by conducting DR testing. Run fire drills and conduct tabletop exercises. Practice restoring data. These inputs will help you understand if your objectives are meaningful and obtainable.
Actionable: Document your RTO and RPO in your DR plans and ensure they align with any business continuity risk management plans or goals around maximum allowable risk tolerance. You may also want to document the assumptions and inputs that formed the RTO and RPO. For instance, how much revenue is lost when a given system is down? Explain how that factor drives your RTO.
Realistic: Don’t let your stakeholders set unachievable objectives. If there is an ask for a very low RTO and/or RPO, help your stakeholder understand exactly what it will take—and how much it will cost—to implement that objective.
Time-bound: The RTO can be defined in seconds up to weeks. The shorter the RTO, the more expensive the investment will be to meet it.
Remember that you’re always balancing RTO and RPO against an unachievable “perfect” state. For instance, you would likely need multiple failover hot sites with replicated data to meet an RTO of seconds of downtime.
RTO is a forward-looking measurement; RPO is a backward-looking measurement that essentially represents the frequency of your backups.
A short RPO means more recent backup data is needed, and, yes, that also means greater investment. RPOs measured in seconds may require high-speed backup technology like continuous replication.
How to discuss RTO and RPO with business leaders
Discussing technical concepts with internal stakeholders can be challenging. To guide the objective-setting discussion with stakeholders, use the following questions as a guide:
Where and how do you store data?
How often does your data change?
What would a minute of downtime cost your department, in terms of revenue, risk, loss of productivity, impact to customers, etc.?
What are the compliance or industry requirements for maintaining sensitive data?
Do you have a way of manually transacting business if service is down?
Your IT department may already be well aware of many of these goals, but it’s good to do a fresh and full inventory of data and data management procedures. For example, even with the rise of shared drives, many employees still save important data locally. Or, there may be business-critical data being saved in services like Microsoft 365 or Kubernetes—and those services are often not adequately backed up.
How do RTO and RPO affect backup strategy?
Your RPO is often more directly related to backup strategy, although RTO certainly informs backup strategy. If you need a very low RPO (i.e., the business can tolerate very little data loss), you must plan to run backups more frequently. This ensures you always have very recent data to recover.
RTO, however, relates more to systems and infrastructure—again, because the objective is about recovery and not just restoring data. RTO will drive investment decisions around backup and DR architecture.
Your backup strategy or tech stack should not dictate either your RTO or your RPO.
First, you should define your RTO and RPO, and then you must determine if changes in backup policy are needed or if you need to update any backup systems in order to reach desired RTOs and RPOs.
Your RTO will drive decisions around backup and DR infrastructure; your RPO will drive decisions around frequency of backup and type of backup.
How does the cloud help companies meet RTO and RPO goals?
Using a public cloud for backup and archive can help you achieve your desired RTO and/or RPO. An obvious example is using cloud to replace LTO tape backup. Tape backup has some of the worst (maybe the worst) RTOs and RPOs. It takes an extraordinarily long time to recover from tape, and backups are likely not as frequent as they should be because tape is often not properly maintained. Migrating your tape backups to a public cloud like Backblaze B2 Cloud Storage is still cost-effective and it will drastically improve RTO and RPO.
If you’re using a hyperscaler like AWS, you may have had to cut back on frequency of backup or needed retention periods due to exorbitant fees. Shifting your backups to Backblaze B2 can help you achieve your goals: Backblaze B2 is one-fifth the cost of AWS S3, you can afford to run and save more frequent backups, thus lowering your overall RPO.
Replication is another technology that can help reduce RTOs. Many enterprise businesses will already have a failover site, but keeping an extra copy of your data in the cloud ensures you can still meet your desired RTO in the case of a DR site or production facility takeout. This is exactly what brought SaaS platform Centerbase to Backblaze.
More commonly, if it’s inordinately expensive to own your own DR site, you can store your backups in Backblaze B2 and utilize Cloud Replication for added redundancy.
RTO and RPO and your business
Ultimately, you should frame your RTO and RPO in terms of business impact. Then, reverse engineer your backup and DR infrastructure to support those objectives. Next, identify the storage systems for your data based on its business criticality and desired RTO and RPO.
Depending on your business goals, you’ll likely use cloud storage services, on-premises storage, or some combination of the two. Regardless of the type of business you run, demonstrating that you have an airtight DR plan with SMART RTO and RPO goals will instill confidence in your business partners, help with cyber insurance eligibility, and shore up your organization’s ability to withstand data disasters.
A well-defined disaster recovery (DR) plan relies heavily on a coordinated incident response team. Think of your incident response team like a pit crew. It’s easy to assume you’ll have a good race when everything is performing smoothly, but the real test comes when something goes wrong—maybe a tire blows or the engine overheats. In those moments, success isn’t about having the best tools in the garage; it’s about having the right team, working together, to quickly solve problems and get back on track.
When your team is facing a disaster recovery scenario, whether it’s a cyber attack, natural disaster, outage, or data breach, the speed and coordination of your team determines how quickly and how well you can move forward. In this post, I’m breaking down how to assemble a team that can respond with precision, minimize downtime, and keep your organization running smoothly when unexpected issues arise.
Establishing key team members, roles, and hierarchy
The incident response team (IRT) is the backbone of your DR response and is responsible for leading the recovery efforts during a disaster. Here’s a breakdown of possible key IRT roles:
Incident commander: Oversees the entire incident response process, making critical decisions and delegating tasks to team members.
Communications lead: Handles external and internal communication, ensuring timely updates for stakeholders and mitigating potential reputational damage.
Documentation lead: Maintains the DR runbook, ensuring its accuracy and updating it with post-incident findings.
Legal counsel: Provides legal guidance and ensures compliance with relevant regulations during the response and recovery process.
Building redundancy
Building redundancy in your IRT allows you to account for team member absences. This includes IT leadership; don’t assume you’ll be in the office when a disaster happens. Assign backup personnel for critical roles within the team to ensure continuity in the event of unforeseen circumstances.
Establish a clear succession plan for leadership roles within the IRT. This ensures a smooth transition if the primary incident commander or other key personnel become unavailable during a disaster.
Establishing a reporting hierarchy
Clearly define a reporting hierarchy within the IRT, outlining who reports to whom and the escalation process for making critical decisions. A clear chain of command during a crisis prevents confusion and delays that could result in prolonged downtime and increased risks.
The importance of clear communication
A critical component of any DR plan is clear communication to employees and executives regarding their specific roles during a security incident. This ensures that the assigned team leader can coordinate a unified response. Remember to include guidelines about incident escalation, as well as agreed-upon methods of communication (e.g., email, direct messaging, video calls, etc.).
Executive sponsorship: Beyond awareness
Executive buy-in is paramount for a successful DR strategy. While awareness of the impact of ransomware attacks has grown over the years, contextualizing DR plans with historical financial impacts, downtime implications, and reputational risk associated with such attacks can help to communicate why DR is a top-line priority.
Tip: Educating executives
Framing the DR plan in terms of cost avoidance, user downtime minimization, and reputational risk mitigation can resonate better with executives. Quantify the potential financial losses from data breaches and system outages to garner executive support for DR initiatives.
Beyond cell phones: Communication channels
Disasters can disrupt traditional communication methods like cell phone service. Develop alternative communication channels for the IRT, such as designated email threads, satellite phones, or pre-arranged conference call bridges. It is imperative to include this information and contact details in your DR runbook for immediate accessibility during crises.
By establishing a well-defined team structure with clear roles, communication protocols, and redundancy measures, enterprise businesses can ensure a coordinated and efficient response to data disasters.
A well-prepared team leads to a resilient recovery
Your DR strategy is only as effective as the team behind it. By defining clear roles, building in redundancy, and establishing a reporting hierarchy, IT leaders can eliminate confusion and accelerate recovery efforts. Moreover, securing executive sponsorship and ensuring clear communication strengthens your ability to respond effectively. DR isn’t just about the plan on paper. It’s about how you execute that plan and set your team up for success.
I’ve heard the horror stories, and I’m sure you have too. A company thinks they’re covered because they have replication running, only to realize too late that replication doesn’t protect against data corruption or ransomware. In a disaster scenario, every copy of their critical data is compromised. And then comes the dreaded question: Do we have a backup?
Many teams—even those with seasoned IT professionals—misunderstand the fundamental difference between backup and replication for disaster recovery (DR). Replication is about availability, or keeping systems running with minimal downtime. Backup is about recoverability, or ensuring you can go back to a known good state.
This post breaks down replication, backup, and their respective roles in disaster recovery in a way that’s easy to share with your team, helping to prevent costly misunderstandings.
What is data replication?
Data replication involves copying and synchronizing data between your primary site and the DR destination in real-time or near real-time. It offers fast failover capabilities as the replicated data at the DR site is constantly updated. However, if malware infects your primary site, it might also replicate to the DR site, rendering the backup compromised.
What is data backup?
Data backup involves creating full and incremental copies of your data and storing them in a separate location from your primary system, typically on a scheduled basis, to prevent loss, corruption, or disasters. A couple key points:
Incremental backups capture changes in data, thus offering a point-in-time recovery option.
Ideally, backups are immutable, meaning they can’t be altered, in order to protect against malware and ransomware by making files and images read-only for safe recovery.
Air-gapped and offline backups can further help resist malware and ransomware attacks by creating a virtual or physical separation from the production network.
Cloud-based backups are a great option for addressing these requirements while offering affordable scaling options as the environment grows.
Replicating backups
A hybrid approach involves replicating your backups to a secondary location, offering a balance between data protection and recovery time. This can be between on-premises and cloud environments, or across multiple cloud targets.
While replicating backups offers additional protection and accessibility for online recovery, the backup images are still subject to ransomware infection. Using immutable backups helps prevent the spread of the infection to recovery sites and backup repositories.
Data backups paired with replication can be an ideal strategy. Full and incremental backups with point-in-time snapshots can provide regular recovery points with replicated copies for remote recovery and additional protection.
Cloud Replication
Backblaze B2 Cloud Replication enables your data to be automatically copied from one location to another for redundancy, compliance, and fast local access. Create 2x backups for a stronger disaster recovery posture. Replicating your Backblaze data is easy and free—no service or egress fees—just the standard Backblaze B2 Cloud Storage rates.
Disaster recovery and backups: Factors to consider when choosing the right approach
The optimal approach to disaster recovery backup and when and how you use replication depends on your specific needs.
For frequently accessed data requiring near-instantaneous recovery, consider a combination of a hot site methodology and real-time data replication. This offers the fastest failover, but can come at a higher cost.
For critical data with acceptable downtime, a warm site with replicated immutable backups at a secondary location (either on-premises or in the cloud) provides a good balance between cost and recovery time. While requiring some manual intervention, it offers protection against malware replicating to the DR site.
For less critical data or archival purposes, cold storage with periodic backups is a cost-effective option. Backups offer a historical record and are less susceptible to malware infection compared to replicated data, particularly if Object Lock is enabled for immutability.
Data replication is important, but it should not be seen as a substitute for backups. Backups offer a required safety net, providing a point-in-time recovery option even if the replicated data is compromised. Selecting the right disaster recovery backup strategy depends on a careful evaluation of your company’s specific needs, budget, and risk tolerance.
By understanding the pros and cons of each option, you can make an informed decision that ensures optimal protection for your critical data in the face of unforeseen disruptions.
If there’s one thing I’ve learned from working with enterprise customers on their cyber resilience postures, it’s this: Downtime caused by disasters can be costly, and every organization should have a disaster recovery (DR) plan in place.
Today, I’m outlining 12 best practices to consider when developing and reviewing your organization’s DR plan to minimize downtime, risk, and unexpected costs in the face of unexpected events.
These key considerations will help your IT team when developing and reviewing a disaster recovery plan.
1. Leave no disaster unidentified
The first step in building a strong DR plan is to identify all potential threats, not just major disasters. Consider “minor” threats like human error or hardware failures that could disrupt security and operations.
2. Plan for the worst (and beyond)
While it’s important to plan for likely threats like ransomware attacks, don’t neglect worst-case scenarios. Develop a plan that can handle a catastrophic event like a natural disaster wiping out your primary site or a widespread communication outage.
3. Ransomware: Your uninvited guest
Ransomware attacks are a major threat. Dedicate a significant portion of your DR plan to addressing ransomware scenarios, including recovery procedures and strategies to minimize the impact of such attacks.
4. Beyond the walls: Cloud catastrophe
Extend your DR plan beyond on-premises threats to include potential disruptions associated with cloud services, such as outages or security breaches. It may seem counterintuitive that we, a cloud provider, are the ones to call this out, but we’re big proponents of the tenet that the one truth about technology is that it will fail. Multi-cloud and hybrid disaster recovery options help reduce the risk of those rare, but highly impactful outages. Cloud provider service level agreements (SLAs) define availability targets (e.g., 99.9% uptime) which can increase your overall data and application availability above on-premises capabilities.
5. Infrastructure independence
Always anticipate potential infrastructure unavailability during a disaster. Plan alternative methods for accessing critical data and systems, including leveraging hot cloud infrastructure as a service (IaaS) solutions as a backup.
6. Think beyond data recovery
A robust DR plan goes beyond just recovering data. It should outline procedures for rebuilding your entire IT environment, including applications, configurations, security, and user accounts. There’s a big gap between restoring data and actual recovery.
7. Plan variations
Develop different versions of your DR plan based on the severity of the incident and the types of incidents your business is most likely to face. This allows for a more targeted response, depending on the specific nature of the disruption.
8. Runbooks: Your DR roadmap
Consider creating predefined “runbooks” that outline specific steps for various disaster scenarios. These detailed documents provide clear instructions for IT staff during a crisis.
9. Recovery is a sprint, but DR planning is a marathon
Modern DR strategies prioritize planning for recovery from the beginning. Verify the usability of your backups and recovered data to ensure their effectiveness during a crisis. Test your restoration procedures regularly to avoid the pitfall of unusable backups during a disaster.
10. Securing resources in advance
Don’t wait for disaster to strike before securing necessary resources. Budgetary approvals, software licenses, and hardware procurement should all be addressed in advance to avoid delays during a crisis.
11. Cyber insurance considerations
If your business has cyber insurance, familiarize yourself with the DR planning requirements outlined in the policy. Understanding the insurance company’s expectations can help you tailor your DR strategy accordingly.
12. Backups are essential, but they’re not the whole plan
As cybercriminals become more sophisticated, they often target backups as well. Backups—once a low-priority just-in-case item—are now mission critical. Backups are a critical foundation for your DR plan, but they are not the entire plan.
A closing note on recovery
Finally, make sure to regularly test and update your DR plan to ensure it remains effective and up to date. By leveraging affordable, secure, cloud-based backup and archive as part of your overall disaster recovery strategy, you can better protect your critical data. The result will minimize downtime, risk, and costs in the face of unexpected events.
It goes without saying (but I will say it anyway) that having a disaster recovery (DR) site is essential to protecting business continuity (BC) in the face of disasters both big and small. However, even for large enterprises, building and maintaining a separate physical facility to store data copies can be cost prohibitive, and it may not make sense operationally.
DR sites differ according to the availability of data for retrieval and by type of ownership (e.g., fully owned or colocated). In recent years, public cloud has also emerged as a viable DR “site”—meaning that backups, production data, and/or virtualized infrastructure can be effectively housed in the cloud.
In this blog, I’ll examine the primary differences and pros and cons between various types of DR sites, and I’ll outline the most important criteria for deciding on the right DR setup for your business.
Proprietary ownership vs. colocation
If your business is able to fully invest in owning a DR site, the obvious upsides are greater control over security and infrastructure. But owning and operating your own site may still not be the most ideal option, given the staffing and expertise required. For many businesses, it doesn’t make sense to invest in owning and operating a data center when that’s not your area of expertise.
That’s why many businesses opt for colocation. It can be a great option for adhering to your DR strategy and your expense limits. However, you must be careful to thoroughly vet the location and provider. Here are a few important points to consider:
Performance: You should understand what kind of equipment is used at the DR site, as well as what kind of durability and availability you can expect. Ensure that the available infrastructure can meet your required recovery time objectives (RTO) and recovery point objectives (RPO)—that is, the maximum amount of downtime your business can withstand and the maximum amount of data your organization can tolerate losing, respectively.
Security: A trustworthy provider should be staffed 24/7/365. Learn how the data center is protected. Are there cameras? Biometric security? How does the data center protect against things like fire and power loss?
Proximity: A data center that’s down the street from your primary location will offer no protection in the case of a regional disaster like wildfire or tornado—events that are unfortunately becoming more and more common. Ideally, you should choose a location that is far from your production facility. This is where the public cloud naturally fits in—but more on that in a bit.
Scalability: Gauge how much data you currently need to store as well as how much you expect to grow in the near future. Find out how much capacity the DR site can support and choose a site that can accommodate your planned growth.
Costs: Get a complete view of your total cost of ownership. This not only includes one time costs to get started and ongoing monthly or yearly expenses, but also potential costs for things like additional support or any capacity you may need to add in the middle of a contract period.
Compliance: Consider what compliance requirements your business must support. Some data centers are SOC 2 compliant; some are not. It’s also important to check your cyber insurance policy requirements. Many policies may require that you keep data backups in a facility that is far from your own. This is exactly the requirement that brought telco AcenTek to Backblaze.
Meeting cyber insurance requirements with the cloud
In order to satisfy cyber insurance policy requirements, AcenTek’s backups needed to be off-site and geographically distant from their own data centers. Backblaze offered a critical feature—immutability and certification as a Veeam Ready Object partner—as well as geographic distance from AcenTek’s own data centers to meet the requirements and protect AcenTek’s business.
Hot, warm, and cold DR sites: Choosing the right strategy
Recovery sites are often referred to by temperature (hot, warm, cold) to describe the speed and importance of applications and data in those protected sites. The ideal DR site temperature depends on your organization’s budget, risk tolerance, and RTOs. Businesses with critical systems requiring near-instantaneous recovery might opt for a hot site. Others might find a warm site or even a cold site a more cost-effective option for less time-sensitive systems.
Hot, warm, and cold: Choosing the right DR site temperature
Hot site
Warm site
Cold site
Description
A fully functional replica of your primary production resources, constantly maintained and ready for immediate failover in the cloud or to a secondary on-premises site.
A pre-configured cloud recovery site or hybrid recovery with hardware and software infrastructure. Requires some manual intervention (e.g., software installation) before becoming operational.
A basic physical facility with essential infrastructure (power, cooling, and network connectivity) requiring significant configuration and installation before use. May also include cold cloud storage.
Pros
Fastest recovery times due to the site’s constant readiness.
A balance between cost and recovery time. Faster than cold sites, but slower than hot sites.
Most cost-effective option, requiring minimal ongoing maintenance.
Cons
This is the most expensive option due to the need for complete infrastructure replication.
Still requires some manual setup, potentially delaying recovery time.
Longest recovery times due to the extensive configuration and installation needed. Or, in the case of cold cloud storage—the time required to retrieve your data.
Example RTO goal times
RTO <15 minutes
RTO <24 hours
RTO >24 hours
Public cloud as virtual DR site
Traditionally, DR for large enterprises would involve building a physical site to support RTO objectives. It’s important to note that building or buying a dedicated DR site might not be the most cost-effective option for all backups. Instead, cloud storage offers a compelling solution specifically for backups, even if you have your own physical DR site.
Why Backblaze works for DR
Cloud storage from a specialized provider like Backblaze is generally more affordable and scalable than on-premises storage solutions or off-site DR facilities, making it a great fit for this purpose. Backblaze offers always hot storage with 3x free egress, meaning data can be immediately recovered when needed without surprise egress bills. In this way, Backblaze B2 Cloud Storage constitutes a virtualized hot DR site.
Cold cloud storage considerations
While some consider cold cloud storage to be the most cost-effective solution, the cost savings of cold storage are often entirely negated by its long retrieval time and egress charges—so much so that it no longer becomes a viable disaster recovery option.
Evaluating cloud storage providers
In a way, you can consider the public cloud very similarly to a colocated DR site. All the same questions apply when choosing between cloud storage providers (CSPs):
Performance: What durability, reliability, and availability does the CSP offer? What kind of throughput do you get on a proof of concept?
Security: Does the CSP staff their data centers 24/7/365? What security processes and procedures are in place?
Proximity: Where are the CSP’s data centers located? Choose one that offers good geographic separation from your production facility while ensuring you can still meet your RTO with latency considered.
Scalability: Cloud storage naturally offers infinite scalability, but it’s vitally important to ask your CSP how they handle things like capacity overages or the need to purchase additional capacity. Some CSPs will charge you excessive fees when you go over capacity, or they may require you to switch to a different pricing model if you need additional storage space in the middle of a contract period.
Costs: Again, you need a complete view of your TCO. Watch out for things like minimum retention periods, egress charges, and other hidden fees.
Compliance: Be careful of CSPs that claim they’re SOC 2 compliant. Sometimes the CSP operates in SOC 2 compliant data centers but the company is not SOC 2 compliant itself. That difference may be meaningful to your company or your own compliance requirements.
Ultimately, you must carefully balance business requirements for RTO and RPO with DR investment costs. Businesses located in likely disaster areas like tornado alley, earthquake-prone zones, or coastal areas are well served by the additional investment in DR infrastructure. But even if your company has its own DR site, public cloud can be a beneficial supplement to your own DR infrastructure.
Aging infrastructure, strained budgets, and exponential data growth create unique challenges for disaster recovery (DR) planning. When assessing your backup and archive infrastructure, you’re probably balancing data governance, data sovereignty requirements, compliance requirements, and the needs of your end users. Many legacy data storage systems can create gaps in an otherwise airtight DR plan.
Today, I’m talking through how to approach infrastructure decisions for your cyber resilience posture. You have a lot of options. On-premises? Cloud services? Hot? Warm? Cold? What combination works best for your needs? Understanding the nuances can help you sharpen your strategy.
Disaster recovery challenges
1. Relying on on-premises backup and archive infrastructure
Traditionally, businesses have relied heavily on on-premises backup solutions. Robust storage systems hold critical data, often backed up to secondary storage within the same physical location. While this approach offers a sense of control, it also presents vulnerabilities.
On-premises backups are at risk of localized events like loss of power, fire, flooding, or other natural disasters. A geographically separate DR site or other far off-site backup is essential for complete protection and compliance. Without this, the organization risks losing critical data in cases of a regional outage or loss of access.
The shift to public cloud and SaaS options opened the door to more secure and reliable data backup and disaster recovery solutions. By utilizing cloud-based storage and backup services, organizations can ensure that their data is protected in multiple locations, reducing the risk of data loss due to localized disasters. Additionally, cloud-based solutions offer scalability and flexibility, allowing organizations to easily expand their storage capacity as needed.
2. Falling into the replication trap
Many businesses have established alternate data centers as a secondary backup layer. However, these sites frequently only use replication technology. This situation can result in a scenario known as the “replication trap.” There is a risk that data compromised by malware is replicated to the DR site, leading to potential data loss.
Off-site, immutable backups, independent of the primary site’s data, are a key component of a robust DR strategy. In cases of malware attacks or accidental data deletion by users, off-site immutable backups allow for data retrieval from a backup saved prior to the incident and reduce possible interruptions.
3. Underestimating LTO limitations
Despite being viewed as a legacy technology, tape backups continue to be used in many organizations due to their reliability and cost-effectiveness. It is common to store tapes in a separate location to diversify data storage geographically, which helps reduce the impact of local disasters on data access and enhances overall data resilience.
Off-site tape backups may increase recoverability but create challenges with recovery time objectives (RTO) because of the increased time it takes to retrieve data from a separate location and restore it using tape technology. Hardware issues can happen often and unexpectedly. Cloud-based data storage and archiving has gained popularity because of higher availability and cost savings over traditional tape backups.
The cost and time required to operate multiple data centers and meet recovery times should also be considered in the requirements for your production and DR infrastructure. Never underestimate the risk to a successful recovery when facing time-consuming tasks like physical site recovery and data restoration from tape.
Cloud-based collaboration and communication tools like Google Drive and Microsoft 365 are commonly used by businesses and yet are often left vulnerable to data loss. Cloud services do not provide sufficient protection and recovery options that organizations likely need.
Businesses often find that the responsibility for backing up this data falls on their own IT, as these services typically operate under a shared responsibility model that doesn’t offer comprehensive backup solutions.
To ensure a reliable DR plan that includes cloud services, you should:
Evaluate granular recovery requirements for productivity platforms like Google Workspace and Microsoft 365.
Evaluate adherence to your long-term backup retention policy keeping in mind the regulations that your business might be subject to.
Determine if data stored in cloud platforms needs to be backed up with immutability due to cyber insurance requirements or other security policies.
Examine best practices for comprehensive, secure data protection for shared cloud drive services and SaaS productivity tools to address the lack of built-in recovery features.
Plan to store true backups of your SaaS data just as you would for any other data. It may seem redundant to back up cloud platforms to the public cloud, but doing so ensures that you have the right point-in-time backups you need and you can recover on your timeline—not Google or Microsoft’s.
Cloud costs will need to factor into decisions for where to store your data. Cloud storage costs should be included as a non-functional requirement to make sure you can achieve your secure recovery goals without sacrificing affordability.
Best practices for cloud-based disaster recovery
Many enterprises rely on cloud-based DR solutions to ensure uninterrupted operations, protect critical data, and maintain customer trust. Unlike traditional DR methods, cloud-based solutions offer scalability, cost-effectiveness, and rapid recovery capabilities. To truly leverage the potential of these systems, it’s important to be aware of some key strategies and considerations to optimize your cloud-based disaster recovery plan, ensuring resilience in the face of unexpected disruptions.
Consider diversifying your cloud portfolio: Using the same cloud service provider for your backups as for your production data may not be necessary, as you don’t need the same level of performance for backup data. You could consider a tiered recovery approach based on the criticality of your applications and data.
Investigate existing tools for cloud compatibility: Many on-premises data protection tools like Synology or QNAP NAS devices also support cloud targets for backup storage. It’s important to match the capabilities of your current backup vendors to your recovery requirements and cloud storage budgets.
Avoid paying for storage you’re not using: Carefully read the fine print when considering cloud storage costs. Hidden fees, minimum retention requirements, and complicated pricing tiers make accurate forecasting difficult and could leave you paying for unused storage just to reach certain discount tiers.
Balance your budget with RTO and RPO targets: Using cloud data storage for production, backups, and archive can lead to some price shock as your environment scales. And moving data to lower cost storage tiers or cold storage may achieve attractive price reductions, but it often comes at the cost of recovery speed and added complexity. Look for a cloud storage provider with transparent pricing that makes it easier to plan your costs.
Finally, you should weigh your cloud-based options to evaluate platform compatibility, ongoing costs, and whether your CSP locks you in or out of specific ecosystems due to high storage costs, data transfer costs, and proprietary features.
Leveraging cloud-based backup and archive infrastructure
Adopting cloud-based disaster recovery best practices is a key consideration for building a resilient and reliable business infrastructure. By developing a well-structured disaster recovery plan, determining the right mix of storage solutions, and optimizing costs with tiered recovery, businesses can minimize downtime and data loss during unexpected events. A proactive approach not only safeguards your organization’s operations but also strengthens customer trust and competitive advantage. In a world where disruptions are inevitable, being prepared is the key to bouncing back stronger and faster.
When it comes to disaster recovery (DR), hope isn’t a plan. Yet I’ve seen the same story play out too many times: Companies find themselves scrambling when the unthinkable happens, discovering that their disaster recovery strategy is, well, full of holes. It’s like packing a parachute: You don’t want to find out what you missed when you’re already falling through the air. From my experience, there are some common mistakes businesses make that can turn a manageable problem into a fire drill.
In this post, I’m sharing the top 10 disaster recovery mistakes I’ve come across when helping businesses think through their disaster recovery posture so that you can strengthen your own safety net. By avoiding these mistakes and implementing a comprehensive DR plan, you can ensure a rapid and efficient recovery from unforeseen disruptions.
1. Proximity paradox
A geographically close disaster recovery site offers limited protection. A natural disaster impacting your primary location could easily disable the nearby DR facility as well. And, if you don’t have a DR site, this could still apply to your business if you keep your backups nearby, such as in a tape storage facility down the road.
How Pittsburg State solved the proximity paradox
Pittsburg State University is located in Kansas in the heart of tornado alley. Disaster planning is nonnegotiable, and the university didn’t want to take chances with their data. See how they set up a robust private cloud with nodes across the state and backed all of their data up to immutable cloud storage with Backblaze B2.
2. Untested backups
Backups that haven’t been restored and verified are unreliable. Regularly test your backups to ensure a smooth recovery process during a disaster.
3. Replication trap
Relying solely on replication for DR creates a single point of failure. If your primary site is compromised, the replicated data at the DR site might be compromised as well. Off-site full and incremental backups are essential.
4. Paper plan peril
A DR plan gathering dust on a shelf is useless. Conduct regular drills to simulate disaster scenarios and expose weaknesses in your plan.
5. Snapshot snafu
Snapshots are not comprehensive backups. Using snapshots for long term storage and retention introduces both technical and compliance risks in relation to how snapshots are managed. This affects both cloud and on-premises platforms.
6. SaaS surprises
Software as a service (SaaS) providers like Microsoft 365 and Google Workspace focus on high availability, but they operate on a shared responsibility model, meaning they may have limited built-in protection and recovery options. You may not be managing servers, but you do need a comprehensive data protection plan including regular, incremental backups outside of the SaaS platform.
7. Unforeseen force majeure
Disasters come in all shapes and sizes. Don’t limit your DR plan to common IT disruptions. Consider scenarios like widespread power outages or communication breakdowns, and plan accordingly. The goal is holistic cyber resilience—not only identifying threats and protecting against them, but also withstanding attacks as they’re happening and responding effectively.
8. Backup infiltration
Bad actors are increasingly targeting backups to increase the chances of a payout. Utilize immutable backups, unchangeable after creation, for an extra layer of protection against ransomware attacks.
9. Cloud drive disasters
Storing data on Google Drive, Dropbox, OneDrive, etc. is incredibly common. But these platforms do not protect against ransomware and provide limited point-in-time recovery options. Cloud drives are not a sufficient backup of your data.
10. Overlooking compliance
Factor in compliance needs when building your data protection and DR strategy. Regulations like HIPAA, GDPR, and others may have security or archival requirements that should be considered in your plan.
Invest in cyber resilience
After working in the disaster recovery space, I can tell you this: It’s not just about having a plan; it’s about having one that works when it counts. The mistakes I’ve covered here are common, but they’re also avoidable. Take the time to address these now, and you’re not only protecting your systems and data, but your company’s future. For me, a strong DR plan is an investment in resilience, and it’s there to catch you when you need it most.
You probably won’t notice a little asterisked footnote tucked at the bottom of the page the first time you read through a cloud storage vendor’s pricing tables. You probably won’t notice it the second or third time either. But you’ll definitely notice it when your bill comes in with charges for data you thought you deleted weeks ago.
That footnote explains an often overlooked challenge to your budget: minimum data retention periods. These policies, used by cloud providers like AWS, Azure, Google Cloud, and Wasabi, can lead to unexpected cost increases and complicated data management strategies.
Today, I’m breaking down cloud storage retention minimums and common scenarios where they directly impact storage budgets and data management policies.
What are minimum data retention periods?
Retention minimums specify the minimum amount of time that data must be stored before it can be deleted, overwritten, or moved to a different storage tier without incurring additional charges.
Cloud storage providers with multiple tiers like AWS or Google Cloud use minimum retention policies to ensure that customers cannot frequently move data between storage tiers to exploit lower-cost storage classes for short-term storage. For cloud providers that have a single class of storage, these policies allow providers to stabilize their resource usage and maintain predictable pricing structures.
Minimum retention periods can vary significantly between providers, and even between different storage tiers offered by the same provider. For example, AWS S3 Standard has no minimum retention period, but S3 Standard-IA has a 30 day minimum, Glacier has a 90 day minimum, and Deep Archive has a 180 day minimum.
Despite their significance, information about these retention periods is often buried in the fine print of service agreements or technical documentation.
What are delete fees?
Delete fees are a direct consequence of deleting or moving files before the retention minimum is met. Cloud providers charge these fees to ensure that the infrastructure allocated for the data is compensated for the resources it would have otherwise used during the retention period. This fee is typically prorated, representing the remaining days in the retention period that the data was meant to occupy in a storage class.
The terms “delete fees,” “minimum storage duration,” and “minimum retention fees” all refer to a similar policy.
How are delete fees incurred?
Early deletion fees can be triggered by various actions, not just the obvious deletion of files. Some examples include:
Moving data from a higher-cost tier to a lower-cost tier before the minimum retention period has been met: This scenario often catches organizations off guard when they attempt to optimize costs by transferring infrequently accessed data to a cheaper storage class.
Overwriting existing files: When a file is overwritten, the cloud provider typically treats this as a delete operation followed by a new write operation. If the original file hasn’t met its minimum retention period, the organization may be charged for the remaining time, even though they’re still using the same amount of storage space.
Implementation of automated lifecycle policies: Many organizations set up rules to automatically move or delete data based on its age or access patterns. However, if these policies don’t account for minimum retention periods, they can inadvertently trigger early delete fees on a large scale.
Renaming files or folders: Even seemingly benign actions like renaming files or folders can sometimes be interpreted as delete-and-rewrite operations by certain cloud storage systems, potentially triggering these fees.
Additionally, in multi-user or multi-team environments, lack of communication about retention policies can lead to unexpected charges. One team might delete or move data without realizing the financial implications for the entire organization.
The financial impact of minimum data retention periods
Minimum data retention periods, particularly in cold storage tiers, can have significant impacts on IT budgets. What may have seemed like a cost-saving storage tier can actually increase expenses when operations require frequent deletions or movements of data before the minimum retention period is over. But even in hot storage, these policies can unexpectedly inflate overall costs.
To illustrate the real-world impact of retention minimums, let’s examine a few common scenarios:
1. Backup strategy
Let’s say you have a 30 day backup strategy for your critical infrastructure, and you opt for Wasabi object storage to save costs vs. AWS. You plan to keep a month’s worth of backups in the cloud and will then replace them with the newer backups.
Wasabi’s minimum retention policy is 90 days for its Pay as You Go storage (and 30 days for its Reserved Capacity Storage).
You store an initial 50TB of backups in Wasabi on Day 1. On Day 31, the older backup is deleted and replaced with the newer backup. So, you incur costs for 30 days of Timed Active Storage (50TB) and 60 days of Timed Deleted Storage (50TB). These charges are incurred every time the backup is replaced.
With Wasabi’s Pay as You Go storage, your monthly bill will look like this:
50TB x $6.99/TB/month x 3= $1048.50
We multiply by 3 because the 90 day minimum retention policy equals three months’ time. One of those you’ve actually stored for, and the other two are because you’ve replaced your backups with the new ones.
Compare this to Backblaze B2 Cloud Storage, which has no minimum retention policy and costs $6 per TB/month for its Pay as You Go storage:
50TB x $6/TB/month = $300
The minimum retention policy effectively triples the anticipated storage expenses. When scaled across multiple backup sets or extended periods, the impact on the IT budget can be substantial.
Delete fees in the real world: California university switches to Backblaze to eliminate surprise bills from Wasabi
Cal Poly Humboldt thought they understood cloud storage provider Wasabi’s pricing, but each month brought unexpected charges for deleted data due to Wasabi’s minimum storage retention policies. This, in turn, caused a chain reaction of calls from the procurement office, buying extra capacity, and then modifying the system to try to avoid further bills. To silence the monthly fire alarms, they switched to Backblaze.
With no retention minimums, Cal Poly Humboldt now knows exactly what their Backblaze costs will be up front. The move was so smooth that they migrated another 100TB from Google’s no-longer-free tier for educational institutions and plan to scale their storage to over a petabyte to back up and safeguard research data.
2. Application storage
In application storage use cases, retention minimums can impact cloud spend significantly when the data has a short lifecycle. Applications with high transaction volumes—such as e-commerce, user-generated content applications, or surveillance platforms—frequently upload and delete as part of their daily operations.
For example, most video surveillance platforms may only need 30 days of history for footage that’s been uploaded and processed, so something like a 90-day retention period doesn’t make financial or operational sense. E-commerce customers can also be affected; these businesses have users that frequently upload and delete content to manage storefronts, creating unpredictable data usage patterns. In these cases, you are at the mercy of your end users—if users churn through files quickly you will pay the retention penalties.
3. Video production
Retention minimums also affect video production workflows particularly when you need to make revisions once a project has been archived in cold storage—a common workflow many studios and broadcasting agencies use to get more affordable storage rates for seldom-accessed data.
Whether due to last minute changes in branding, edits to visuals, or adjustments to sound, the project needs to be pulled from storage for further modification. Because the files were moved to colder storage under a 90 day retention policy, accessing and modifying them before that period ends can trigger significant early delete fees.
If you routinely archive files immediately after a project completes anticipating that no further changes will be required, these early delete fees can add up quickly.
The hidden complexities of minimum data retention periods
Retention minimums can significantly impact your bottom line. These policies, often buried in the fine print, can lead to unexpected costs and complicate data management strategies across various industries.
Understanding the nuances of minimum data retention periods and their associated costs is crucial for developing an effective and economically sound cloud storage strategy. It enables organizations to make more informed decisions, avoid unexpected expenses, and better align their storage choices with their specific data management needs and budget constraints.
When you think about cloud performance, metrics like latency and throughput are probably the first things that come to mind. We covered those metrics pretty extensively here and here. So, today, I’m walking through some factors that affect cloud performance that may not get talked about as often, including:
These factors may not be “surprising” per se especially if you remember the pain of trying to download The Matrix over dial up. But they are all things that you should consider (and that you have more control over) when thinking about cloud performance overall.
Let’s dig in.
1. The size of your files
This one is pretty obvious. Larger files take longer because they require more data to be transferred. If you have a 10Mbps upload connection, a 1GB file will take approximately 800 seconds (13 minutes and 20 seconds) to upload, whereas a 100MB file will take about 80 seconds (a minute and 20 seconds). Most enterprise-grade internet connections offer higher upload speeds, but 10Mbps makes the math approachable for the sake of argument.
Small files—that is, those less than 5GB—can be uploaded in a single API call. (Note: this can vary based on cloud storage provider and configuration.) Larger files up to 10TB can be uploaded as “parts” in multiple API calls. Each part has to be a minimum of 5MB and a maximum of 5GB.
You’ll notice that there is quite an overlap here! For uploading files between 5MB and 5GB, is it better to upload them in a single API call, or split them into parts? What is the optimum part size? For backup applications, which typically split all data into equally sized blocks, storing each block as a file, what is the optimum block size? As with many questions, the answer is: it depends.
2. The number of parts you upload or download
Each API call incurs a more-or-less fixed overhead due to latency. For a 1GB file, assuming a single thread of execution, uploading all 1GB in a single API call will be faster than 10 API calls each uploading a 100MB part, since those additional nine API calls each incur some latency overhead. So, bigger is better, right?
3. Block (part) size
Not necessarily, and that brings us to part size. Multi-threading, as mentioned above, affords us the opportunity to upload multiple parts simultaneously, which improves performance—but there are trade-offs. Typically, each part must be stored in memory as it is uploaded, so more threads means more memory consumption. If the number of threads multiplied by the part size exceeds available memory, then either the application will fail with an out of memory error, or data will be swapped to disk, reducing performance.
Downloading data offers even more flexibility, since applications can specify anyportion of the file to download in each API call. Whether uploading or downloading, there is a maximum number of threads that will drive throughput to consume all of the available bandwidth. Exceeding this maximum will consume more memory, but provide no performance benefit.
So, what to do to get the best performance possible for your use case?
Simple: Customize your settings
Most backup and file transfer tools allow you to configure the number of threads and the amount of data to be transferred per API call, whether that’s block size or part size. If you are writing your own application, you should allow for these parameters to be configured. When it comes to deployment, some experimentation may be required to achieve maximum throughput given available memory.
The big takeaway: When it comes to cloud performance, the metrics you need to care about and the performance you actually need are highly dependent on your use case, your own infrastructure, your workload, and all the network connections between your infrastructure and the cloud provider as well. So, when you’re deciding how to store and use your data, it’s worth taking some extra time to consider the above factors for optimum performance.
Availability, time to first byte, throughput, durability—there are plenty of ways to measure “performance” when it comes to cloud storage. But, which measure is best and how should performance factor in when you’re choosing a cloud storage provider? Other than security and cost, performance is arguably the most important decision criteria, but it’s also the hardest dimension to clarify. It can be highly variable and depends on your own infrastructure, your workload, and all the network connections between your infrastructure and the cloud provider as well.
Today, I’m walking through how to think strategically about cloud storage performance, including which metrics matter and which may not be as important for you.
First, What’s Your Use Case?
The first thing to keep in mind is how you’re going to be using cloud storage. After all, performance requirements will vary from one use case to another. For instance, you may need greater performance in terms of latency if you’re using cloud storage to serve up software as a service (SaaS) content; however, if you’re using cloud storage to back up and archive data, throughput is probably more important for your purposes.
For something like application storage, you should also have other tools in your toolbox even when you are using hot, fast, public cloud storage, like the ability to cache content on edge servers, closer to end users, with a content delivery network (CDN).
Ultimately, you need to decide which cloud storage metrics are the most important to your organization. Performance is important, certainly, but security or cost may be weighted more heavily in your decision matrix.
What Is Performant Cloud Storage?
Performance can be described using a number of different criteria, including:
Latency
Throughput
Availability
Durability
I’ll define each of these and talk a bit about what each means when you’re evaluating a given cloud storage provider and how they may affect upload and download speeds.
Latency
Latency is defined as the time between a client request and a server response. It quantifies the time it takes data to transfer across a network.
Latency is primarily influenced by physical distance—the farther away the client is from the server, the longer it takes to complete the request.
If you’re serving content to many geographically dispersed clients, you can use a CDN to reduce the latency they experience.
Latency can be influenced by network congestion, security protocols on a network, or network infrastructure, but the primary cause is generally distance, as we noted above.
Downstream latency is typically measured using time to first byte (TTFB). In the context of surfing the web, TTFB is the time between a page request and when the browser receives the first byte of information from the server. In other words, TTFB is measured by how long it takes between the start of the request and the start of the response, including DNS lookup and establishing the connection using a TCP handshake and TLS handshake if you’ve made the request over HTTPS.
Let’s say you’re uploading data from California to a cloud storage data center in Sacramento. In that case, you’ll experience lower latency than if your business data is stored in, say, Ohio and has to make the cross-country trip. However, making the “right” decision about where to store your data isn’t quite as simple as that, and the complexity goes back to your use case. If you’re using cloud storage for off-site backup, you may wantyour data to be stored farther away from your organization to protect against natural disasters. In this case, performance is likely secondary to location—you only need fast enough performance to meet your backup schedule.
Using a CDN to Improve Latency
If you’re using cloud storage to store active data, you can speed up performance by using a CDN. A CDN helps speed content delivery by caching content at the edge, meaning faster load times and reduced latency.
Edge networks create “satellite servers” that are separate from your central data server, and CDNs leverage these to chart the fastest data delivery path to end users.
Throughput
Throughput is a measure of the amount of data passing through a system at a given time.
If you have spare bandwidth, you can use multi-threading to improve throughput.
Cloud storage providers’ architecture influences throughput, as do their policies around slowdowns (i.e. throttling).
Throughput is often confused with bandwidth. The two concepts are closely related, but different.
To explain them, it’s helpful to use a metaphor: Imagine a swimming pool. The amount of water in it is your file size. When you want to drain the pool, you need a pipe. Bandwidth is the size of the pipe, and throughput is the rate at which water moves through the pipe successfully. So, bandwidth affects your ultimate throughput. Throughput is also influenced by processing power, packet loss, and network topology, but bandwidth is the main factor.
Assuming you have some bandwidth to spare, one of the best ways to improve throughput is to enable multi-threading. Threads are units of execution within processes. When you transmit files using a program across a network, they are being communicated by threads. Using more than one thread (multi-threading) to transmit files is, not surprisingly, better and faster than using just one (although a greater number of threads will require more processing power and memory). To return to our water pipe analogy, multi-threading is like having multiple water pumps (threads) running to that same pipe. Maybe with one pump, you can only fill 10% of your pipe. But you can keep adding pumps until you reach pipe capacity.
When you’re using cloud storage with an integration like backup software or a network attached storage (NAS) device, the multi-threading setting is typically found in the integration’s settings. Many backup tools, like Veeam, are already set to multi-thread by default. Veeam automatically makes adjustments based on details like the number of individual backup jobs, or you can configure the number of threads manually. Other integrations, like Synology’s Cloud Sync, also give you granular control over threading so you can dial in your performance.
Still confused about threads? Learn more in our deep dive, including what’s going on in this diagram.
That said, the gains from increasing the number of threads are limited by the available bandwidth, processing power, and memory. Finding the right setting can involve some trial and error, but the improvements can be substantial (as we discovered when we compared download speeds on different Python versions using single vs. multi-threading).
What About Throttling?
One question you’ll absolutely want to ask when you’re choosing a cloud storage provider is whether they throttle traffic. That means they deliberately slow down your connection for various reasons. Shameless plug here: Backblaze does not throttle, so customers are able to take advantage of all their bandwidth while uploading to B2 Cloud Storage. Amazon and many other public cloud services do throttle.
Upload Speed and Download Speed
Your ultimate upload and download speeds will be affected by throughput and latency. Again, it’s important to consider your use case when determining which performance measure is most important for you. Latency is important to application storage use cases where things like how fast a website loads can make or break a potential SaaS customer. With latency being primarily influenced by distance, it can be further optimized with the help of a CDN. Throughput is often the measurement that’s more important to backup and archive customers because it is indicative of the upload and download speeds an end user will experience, and it can be influenced by cloud storage provider practices, like throttling.
Availability
Availability is the percentage of time a cloud service or a resource is functioning correctly.
Make sure the availability listed in the cloud provider’s service level agreement (SLA) matches your needs.
Keep in mind the difference between hot and cold storage—cold storage services like Amazon Glacier offer slower retrieval and response times.
Also called uptime, this metric measures the percentage of time that a cloud service or resource is available and functioning correctly. It’s usually expressed as a percentage, with 99.9% (three nines) or 99.99% (four nines) availability being common targets for critical services. Availability is often backed by SLAs that define the uptime customers can expect and what happens if availability falls below that metric.
You’ll also want to consider availability if you’re considering whether you want to store in cold storage versus hot storage. Cold storage is lower performing by design. It prioritizes durability and cost-effectiveness over availability. Services like Amazon Glacier and Google Coldline take this approach, offering slower retrieval and response times than their hot storage counterparts. While cost savings is typically a big factor when it comes to considering cold storage, keep in mind that if you do need to retrieve your data, it will take much longer (potentially days instead of seconds), and speeding that up at all is still going to cost you. You may end up paying more to get your data back faster, and you should also be aware of the exorbitant egress fees and minimum storage duration requirements for cold storage—unexpected costs that can easily add up.
Cold
Hot
Access Speed
Slow
Fast
Access Frequency
Seldom or Never
Frequent
Data Volume
Low
High
Storage Media
Slower drives, LTO, offline
Faster drives, durable drives, SSDs
Cost
Lower
Higher
Durability
Durability is the ability of a storage system to consistently preserve data.
Durability is measured in “nines” or the probability that your data is retrievable after one year of storage.
We designed the Backblaze B2 Storage Cloud for 11 nines of durability using erasure coding.
Data durability refers to the ability of a data storage system to reliably and consistently preserve data over time, even in the face of hardware failures, errors, or unforeseen issues. It is a measure of data’s long-term resilience and permanence. Highly durable data storage systems ensure that data remains intact and accessible, meeting reliability and availability expectations, making it a fundamental consideration for critical applications and data management.
We usually measure durability or, more precisely annual durability, in “nines”, referring to the number of nines in the probability (expressed as a percentage) that your data is retrievable after one year of storage. We know from our work on Drive Stats that an annual failure rate of 1% is typical for a hard drive. So, if you were to store your data on a single drive, its durability, the probability that it would not fail, would be 99%, or two nines.
The very simplest way of improving durability is to simply replicate data across multiple drives. If a file is lost, you still have the remaining copies. It’s also simple to calculate the durability with this approach. If you write each file to two drives, you lose data only if both drives fail. We calculate the probability of both drives failing by multiplying the probabilities of either drive failing, 0.01 x 0.01 = 0.0001, giving a durability of 99.99%, or four nines. While simple, this approach is costly—it incurs a 100% overhead in the amount of storage required to deliver four nines of durability.
Erasure coding is a more sophisticated technique, improving durability with much less overhead than simple replication. An erasure code takes a “message,” such as a data file, and makes a longer message in a way that the original can be reconstructed from the longer message even if parts of the longer message have been lost.
The durability calculation for this approach is much more complex than for replication, as it involves the time required to replace and rebuild failed drives as well as the probability that a drive will fail, but we calculated that we could take advantage of erasure coding in designing the Backblaze B2 Storage Cloud for 11 nines of durability with just 25% overhead in the amount of storage required.
How does this work? Briefly, when we store a file, we split it into 16 equal-sized pieces, or shards. We then calculate four more shards, called parity shards, in such a way that the original file can be reconstructed from any 16 of the 20 shards. We then store the resulting 20 shards on 20 different drives, each in a separate Storage Pod (storage server).
Note: As hard disk drive capacity increases, so does the time required to recover after a drive failure, so we periodically adjust the ratio between data shards and parity shards to maintain our eleven nines durability target. Consequently, our very newest vaults use a 15+5 scheme.
If a drive does fail, it can be replaced with a new drive, and its data rebuilt from the remaining good drives. We open sourced our implementation of Reed-Solomon erasure coding, so you can dive into the source code for more details.
In addition to bandwidth and latency, there are a few additional factors that impact cloud storage performance, including:
The size of your files.
The number of files you upload or download.
Block (part) size.
The amount of available memory on your machine.
Small files—that is, those less than 5GB—can be uploaded in a single API call. Larger files, from 5MB to 10TB, can be uploaded as “parts”, in multiple API calls. You’ll notice that there is quite an overlap here! For uploading files between 5MB and 5GB, is it better to upload them in a single API call, or split them into parts? What is the optimum part size? For backup applications, which typically split all data into equal-sized blocks, storing each block as a file, what is the optimum block size? As with many questions, the answer is that it depends.
Remember latency? Each API call incurs a more-or-less fixed overhead due to latency. For a 1GB file, assuming a single thread of execution, uploading all 1GB in a single API call will be faster than ten API calls each uploading a 100MB part, since those additional nine API calls each incur some latency overhead. So, bigger is better, right?
Not necessarily. Multi-threading, as mentioned above, affords us the opportunity to upload multiple parts simultaneously, which improves performance—but there are trade-offs. Typically, each part must be stored in memory as it is uploaded, so more threads means more memory consumption. If the number of threads multiplied by the part size exceeds available memory, then either the application will fail with an out of memory error, or data will be swapped to disk, reducing performance.
Downloading data offers even more flexibility, since applications can specify anyportion of the file to download in each API call. Whether uploading or downloading, there is a maximum number of threads that will drive throughput to consume all of the available bandwidth. Exceeding this maximum will consume more memory, but provide no performance benefit. If you go back to our pipe analogy, you’ll have reached the maximum capacity of the pipe, so adding more pumps won’t make things move faster.
So, what to do to get the best performance possible for your use case? Simple: customize your settings.
Most backup and file transfer tools allow you to configure the number of threads and the amount of data to be transferred per API call, whether that’s block size or part size. If you are writing your own application, you should allow for these parameters to be configured. When it comes to deployment, some experimentation may be required to achieve maximum throughput given available memory.
How to Evaluate Cloud Performance
To sum up, the cloud is increasingly becoming a cornerstone of every company’s tech stack. Gartner predicts that by 2026, 75% of organizations will adopt a digital transformation model predicated on cloud as the fundamental underlying platform. So, cloud storage performance will likely be a consideration for your company in the next few years if it isn’t already.
It’s important to consider that cloud storage performance can be highly subjective and heavily influenced by things like use case considerations (i.e. backup and archive versus application storage, media workflow, or another), end user bandwidth and throughput, file size, block size, etc. Any evaluation of cloud performance should take these factors into account rather than simply relying on metrics in isolation. And, a holistic cloud strategy will likely have multiple operational schemas to optimize resources for different use cases.
Wait, Aren’t You, Backblaze, a Cloud Storage Company?
Why, yes. Thank you for noticing. We ARE a cloud storage company, and we OFTEN get questions about all of the topics above. In fact, that’s why we put this guide together—our customers and prospects are the best sources of content ideas we can think of. Circling back to the beginning, it bears repeating that performance is one factor to consider in addition to security and cost. (And, hey, we would be remiss not to mention that we’re also one-fifth the cost of AWS S3.) Ultimately, whether you choose Backblaze B2 Cloud Storage or not though, we hope the information is useful to you. Let us know if there’s anything we missed.
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.