Tag Archives: Hybrid Cloud

Introducing Genblaze: A Python SDK for Generative Media Pipelines

Post Syndicated from Jeronimo De Leon original https://www.backblaze.com/blog/introducing-genblaze-a-python-sdk-for-generative-media-pipelines/
Isometric illustration of multiple monitors displaying pixelated data visualizations in a purple, blue, and red color scheme, representing generative AI media pipelines.

A year ago, a good video model was a novelty. Today there are at least six worth using, and most of the teams we talk to are wiring up two or three of them into the same product, alongside image models, voice synthesis, and music generation. The hard question isn’t whether you can generate this kind of media. It’s how to build a pipeline that handles five providers without falling over.

That’s why we built Genblaze, an open-source Python SDK from Backblaze for building generative media pipelines: one API across video, image, and audio providers, swappable models, durable object storage, and a SHA-256-verified provenance manifest on every run.

The pipeline is becoming the moat

Models are commoditizing. New video, image, and audio releases drop every couple of months, and each one tends to be the best at one specific thing and middling at the rest. Nobody we work with is betting on a single provider anymore. They build a portfolio and configure fallbacks.

The pipeline is what stays. It’s where you’ve figured out which model handles which shot type and which voice fits which brand. It’s where retry logic and output guards live, and where your audit trail comes from. That work survives the next model release. The prompts you tuned for last quarter’s hero model don’t.

For a pipeline to actually be durable, though, it has to be reactive. Hard-coding one provider, blocking on every step, and returning a single synchronous result is fine for a demo. In production it ages out in weeks. The pipelines that hold up stream progress as events, fan out concurrent work, handle backpressure from slow providers, and let you add a new model with a one-line change.

That’s what Genblaze is designed to be. One pipeline object, every provider behind the same surface, and a new model is one more .step().

A workflow that uses five providers

Here’s a concrete example: producing a short brand film from a one-paragraph brief.

1. Storyboard frames. Lock the visual direction with Seedream 5.0 Lite or FLUX via GMI Cloud, or Imagen on Google.

2. Animate the approved frame. Kling image-to-video on GMI Cloud, Veo on Google, Runway Gen-4 Turbo, or Luma Ray-2. They’re good at different shot types, so we usually try two and pick. Setting chain=True on the pipeline passes the image from step one into the video step automatically.

3. Score and sound design. Music from Stability AI’s Stable Audio or GMI Cloud’s MiniMax. Ambient effects and voiceover from ElevenLabs. LMNT for low-latency text to speech (TTS) when responsiveness matters.

4. Upscale. There’s an upscale step type built in. Route the rendered video through a Replicate upscaler like Real-ESRGAN to hit delivery resolution.

5. Classify and tag. Use a vision-capable chat() call to tag scenes, run brand safety checks, or generate accessibility metadata. Gemini 2.5, GPT-4o, or Llama 3.2 Vision on GMI Cloud all handle this.

That’s five providers across five different model types, defined in one pipeline. The same retry behavior, fallback chains, and provenance manifest apply to every step.

from genblaze_core import Pipeline, Modality
from genblaze_gmicloud import (
GMICloudImageProvider, GMICloudVideoProvider, GMICloudAudioProvider,
)
from genblaze_replicate import ReplicateProvider
from genblaze_google import GeminiChatProvider

run, manifest = (
Pipeline("brand-film", chain=True)
.step(GMICloudImageProvider(), model="seedream-5.0-lite", prompt="...", modality=Modality.IMAGE)
.step(GMICloudVideoProvider(), model="Kling-Image2Video-V2.1-Master", prompt="...", modality=Modality.VIDEO)
.step(GMICloudAudioProvider(), model="minimax-music-2.5", prompt="...", modality=Modality.AUDIO)
.step(ReplicateProvider(), model="nightmareai/real-esrgan", step_type="upscale")
.step(GeminiChatProvider(), model="gemini-2.5-pro", step_type="classify",
prompt="Tag scenes, return JSON with shots, mood, brand-safety flags.")
.run(sink=storage, timeout=900)
)

Swap any step for a different provider and nothing else in the pipeline has to change.

Provenance

Every run produces a canonical, hash-bound manifest that records the provider, model, prompt, parameters, timestamps, and the URI of every asset it produced. You can embed it directly into the output file (.mp4, .png, .jpg, .webp, .mp3, .wav are all supported by the matching media handler), or persist it as a sidecar JSON.

The hash is deterministic, so anyone downstream can verify the file by calling manifest.verify(). The same manifest is replayable: genblaze replay manifest.json reconstructs the run with the same parameters. And because every manifest carries a parent_run_id, you can trace a v3 video back through v2 and v1, including the fork where you tried Runway instead of Kling.

If you’re building customer-facing pipelines, this is what gets you from “we generated this” to “here’s the proof.”

Storage

Assets and manifests land wherever you want. We default to Backblaze B2, which the SDK wires up with ObjectStorageSink(S3StorageBackend.for_backblaze("my-bucket")) and which gives you durable URLs that don’t expire and don’t need credentials to fetch. The same sink works against any S3-compatible store: AWS S3, Cloudflare R2, MinIO.

A few B2 features pair particularly well with this kind of pipeline.

Event Notifications fire to a webhook, queue, or function endpoint when an asset or manifest lands. That gives you a clean way to kick off downstream encoding, indexing, or moderation without polling.

Object Lock lets you write manifests under a retention policy that nobody (not even the account root) can overwrite until the window expires. Combined with the SHA-256 hash inside the manifest, you’ve got cryptographic integrity and storage-layer immutability.

Lifecycle rules handle the cleanup. Final assets and manifests stay around as long as you want them to. Storyboard iterations, rejected takes, and pre-upscale renders prune themselves on whatever schedule you set.

Partnering with GMI Cloud: a unified AI inference platform for open source

GMI Cloud is a unified AI inference platform for open source. It supports LLM, image, video, and multimodal inference through one consistent API. The catalog covers Seedance, Kling, Veo, and Wan for video; Seedream and FLUX for image; MiniMax for music; ElevenLabs voices; and Llama, DeepSeek, and Qwen for chat and multimodal. One API key reaches all of it.

The genblaze-gmicloud adapter maps GMI’s image, video, audio, and chat endpoints onto the pipeline surface and tracks their catalog as new models ship. The first sample app below uses it heavily.

Two sample apps

genblaze-gmicloud-pipeline goes deep on a single provider. A prompt becomes an anchor image via seedream-5.0-lite. You iterate by passing the current image to flux-kontext-pro for reference-based refinement. Once you approve a frame, the app fans out concurrently to three video models (Kling-Image2Video-V2.1-Master, wan2.6-i2v, pixverse-v5.6-i2v). Manifests get written to B2 next to the assets, and the Genblaze integration sits in a single ~100-line file.

genblaze-gen-media-multi-provider-sample is the workflow above end to end. One sentence becomes a narrated, scored, captioned MP4. gpt-4.1-nano writes the storyboard, Imagen 4 produces the keyframes, Decart Lucy or GMI Cloud Kling animates them, NVIDIA Magpie TTS narrates, GMI Cloud MiniMax scores, and ffmpeg composes the final video. Five providers, one pipeline, every artifact ending up in B2 with a verifiable manifest.

Both are MIT-licensed. Clone, fill in .env, run. GMI Cloud docs can be found here. 

Get started

bash

pip install genblaze

That umbrella installs genblaze-core plus the B2/S3 storage backend, which is enough for a working provenance pipeline. Add genblaze[gmicloud], genblaze, or genblaze[all] to pull in providers.

Where this goes

Most of the interesting work in generative media is happening above the models now, in the pipelines that string them together. Whatever model you’re using today probably won’t be your favorite in six months. The orchestration around it is what lasts.

Genblaze is what we built. It’s MIT-licensed and lives at github.com/backblaze-labs/genblaze.

The post Introducing Genblaze: A Python SDK for Generative Media Pipelines appeared first on Backblaze Blog | Cloud Storage & Cloud Backup
Network Stats for Q1 2026: Neocloud Traffic Trends

Post Syndicated from Brent Nowak original https://www.backblaze.com/blog/network-stats-for-q1-2026-neocloud-traffic-trends/

A decorative image with the words Q1 2026 Network Stats.

Welcome to our second quarterly Network Stats report covering Q1 of 2026. Along with Drive Stats and Performance Stats, Network Stats pulls back the curtain on real-world infrastructure data, particularly how network-level analytics reflect emerging AI industry trends and usage patterns. 

Get more Network Stats (and the details of the dataset)

If you are curious about what metrics we’re recording and how we classify data in this series, check out the details outlined in our Q3 2025 Network Stats  and Q4 2025 Network Stats report.

One of the roles of the Network Engineering (NetEng) team at Backblaze is to monitor how traffic moves into, out of, and across our platform—not just day-to-day, but over time as customer behavior and industry dynamics evolve. Right now, few forces are reshaping networks faster than AI. 

With the launch of B2 Overdrive in April 2025, we built a direct, high-performance path between our storage layers and neoclouds where processing, inference, and modeling take place. It has given us a front-row seat to the impact of AI and how network behavior is changing with it. This quarter, in addition to our regular data analysis, we’ve added some geographic heatmaps to understand where and how data is moving. 

Join us live for the webinar

Join us live for the Q1 2026 Network Stats webinarMonday, May 4, 2026 at 11:30 a.m. PT / 2:30 p.m. PT. We’ll explore where AI traffic concentrates, how high-magnitude data flows behave, and what early indicators suggest about the future of AI-native infrastructure design.

Can’t make it live, or reading this article after-the-fact? Sign up anyway and catch the recording on demand.

Get Inside Real AI Network Flows

AI: The elephant in the room

AI workflows don’t just need a place to store data, they need to be able to move it quickly, easily, and nearly constantly for short bursts. Large, multi-petabyte datasets are ingested, transformed, exported for training, pulled back for evaluation, and periodically refreshed as models evolve.  

Backblaze plays a key role at both ends of that lifecycle. We serve as a durable storage layer for the initial data ingestion, and as the high-throughput source feeding model training, evaluation, and validation to whatever best neocloud is suitable at the moment. Once that model has been trained, it needs to be stored, served, and periodically retrained, where we serve as the storage medium.

From a network perspective, this represents a meaningful shift from diffuse, internet-style traffic patterns to large, high-bandwidth flows between a smaller set of endpoints typical of AI-centric infrastructure.

Trends and spring renewal

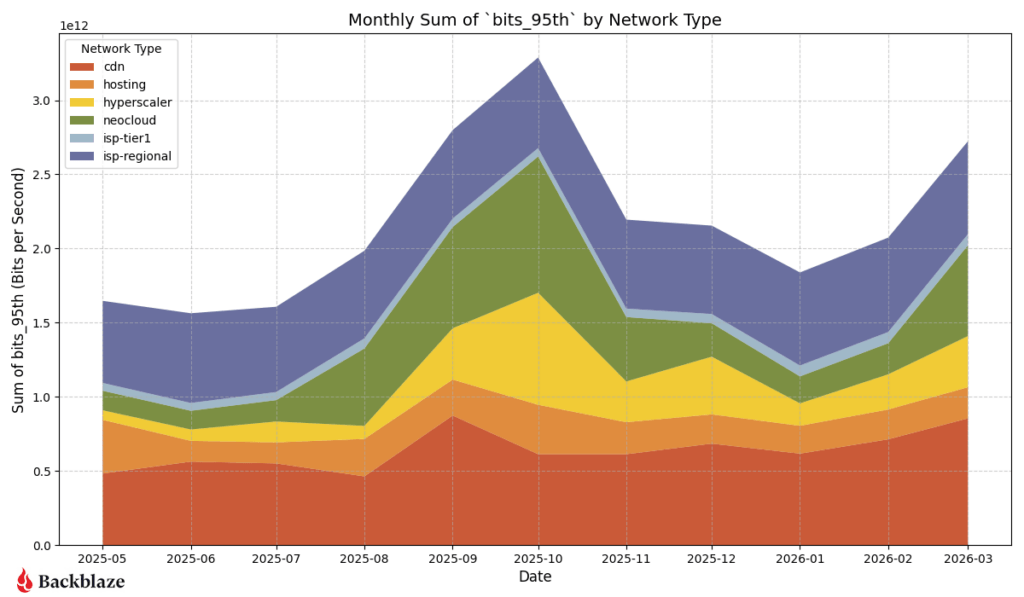
The defining theme of the quarter is “winter freeze” as we observed what looks to be a quiet period of Neocloud and hyperscaler traffic over the winter months with an uptick in March. 

The stacked area graph below shows total traffic by network type over time updated with the most current data. Hosting and internet service provider (ISP) traffic stayed largely within historical norms reflecting steady-state usage patterns. Three slices stand out this quarter:

  • CDN traffic: Increase in CDN traffic over the winter months.
  • Neocloud traffic: After the October 2025 peak, we saw a decline in neocloud traffic heading into January. The winter months were a low volume period with an upward trend observed February into March 2026.
  • Hyperscaler traffic: Hyperscaler traffic also followed the Neocloud pattern of a low period during winter with an upward trend in March 2026.

With more than three quarters of data at our disposal, we can now start to see some trends over time. What do we think is happening? 

This could be an indication of the human element where the business cycle has a lot of downtime in the winter months—all of our code, infrastructure, computing jobs, and new innovations involve people somewhere along the chain and we all (hopefully) tend to take more time off in the winter months.

Another hypothesis is that our numbers only show bits transferred over our network links over time. If a large dataset has been stored with us, there may not need to be an update to the large stored dataset for a number of months as code and models are refined, and then suddenly a large amount of new data makes its way over our network links. Perhaps a combination of both—human and training lifecycle?

We’ll be tracking these metrics and updating in future reports, so this high-level view of network traffic segmented by network type will be interesting to watch.

Chart overview

Now let’s take a deep dive into our data and answer these questions:

Quarter over quarter heatmaps: How and where data moves

To better understand our network activity, we isolated variables like region and types of provider. Let’s look at the following dimensions: 

  1. Total traffic volume: Where did we send and receive the most traffic? 
  2. Magnitude: Where were the data transfers with the most bits per unique IP address?
  3. Uniqueness: What does the number of distinct IP addresses look like? 

Quick terminology refresher

  • Regions
    • US-West: Our largest and longest-running region
    • US-East: Region with the most observed proximity to neocloud infrastructure
    • CA-East: Our newest region in Canada. 
  • Network Types
    • CDN: Networks that use Backblaze as an origin store for content delivery 
    • Hosting: Traditional hosting providers that runs workloads like physical or virtual servers for web, database, or application tasks
    • Hyperscaler: Large, traditional cloud providers
    • ISP Regional: Local or regional ISPs, think of these as the “last mile” paths as these networks are very close to customer equipment and efficient 
    • ISP Tier1: National or international ISPs that carry our traffic long distances
    • Neocloud: AI -focused compute networks

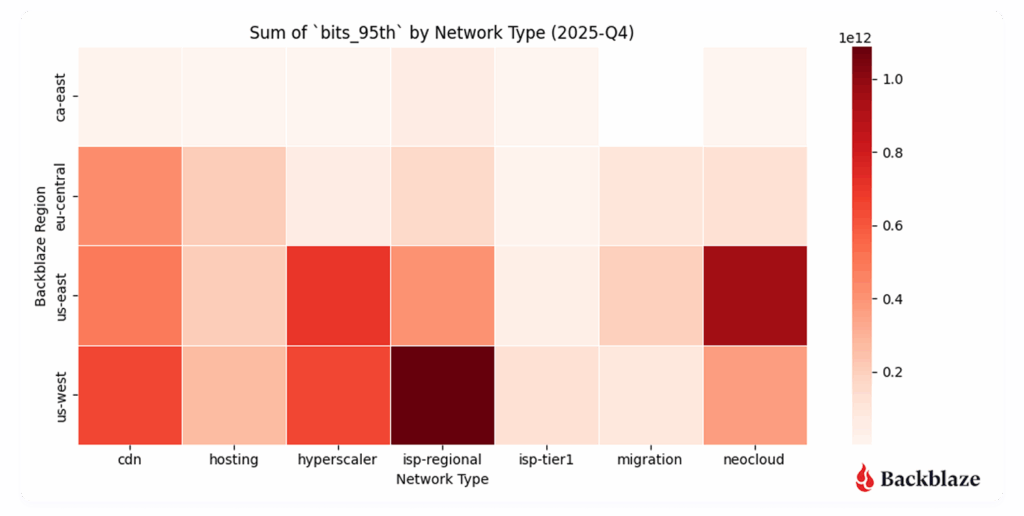
Heatmap #1: Where did we send and receive the most traffic?

US-West ↔ ISP-Regional traffic continues to be a hotspot on the heatmap, as expected. This region has the largest footprint behind it and connections to internet exchanges (IX). This quarter, with a lull in neocloud and hyperscaler traffic over the winter period, we saw an increase in traffic to our CDN partners. The amount of traffic to CDN networks in the US-West, US-East, and EU-Central regions all increased quarter over quarter.

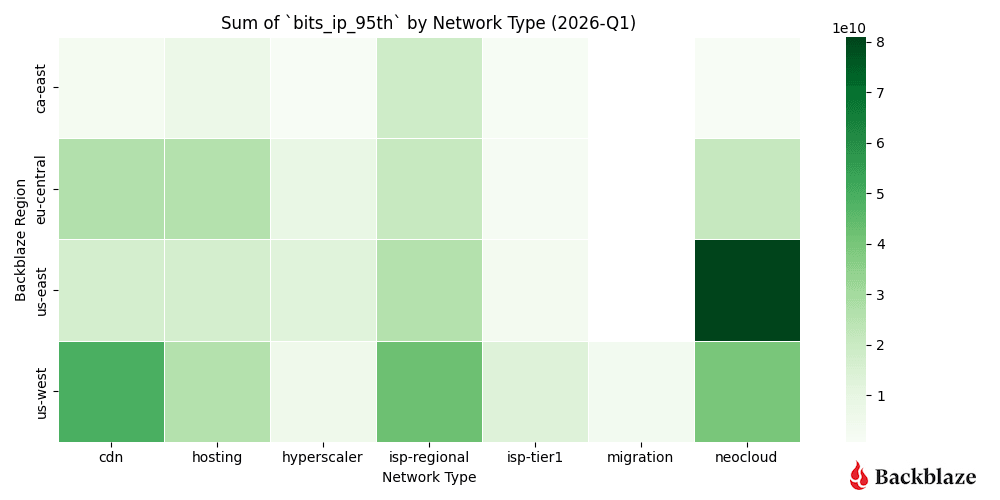
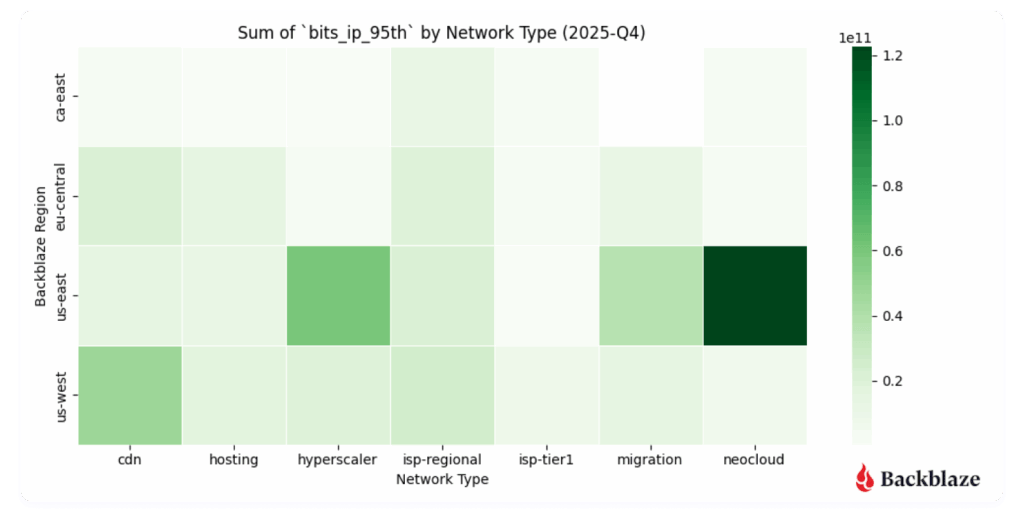
Heatmap #2: Where were the data transfers with the most magnitude (bits per IP address)?

Another metric we record is bits per IP or what we term “magnitude.” This combination of the amount of traffic transferred with how many actors are involved per network is a good proxy to measure how heavy or impactful individual data flows are. In short:

  • High volume, many IPs: Easier to distribute and load-balance across infrastructure. And many source and destination pairs means that we can traffic engineer at the WAN layer, sending some traffic over one provider and some over another.
  • High volume, few IPs: More difficult, but more interesting, from a NetEng perspective. 

Despite the total amount of traffic decreasing over the winter months for neocloud traffic, the magnitude of neocloud transfers still remains high. This speaks to the nature of the traffic pattern—when a GPU/compute cluster is ingesting or producing data, it does so at a high bitrate with just a few number of unique endpoints talking to each other.

As expected, the concentration of our magnitude metric is high for our US-East cluster, with an uptick in concentration in US-West and EU-Central. Where specifically is this new concentration in these regions? Spoiler: We explore neocloud traffic later in the report with geographical data!

As with last quarter, we see a high concentration of neoclouds in US-East, but our new heatmap also shows a rising activity in US-West and EU-Central. We also see more distribution in other use cases. 

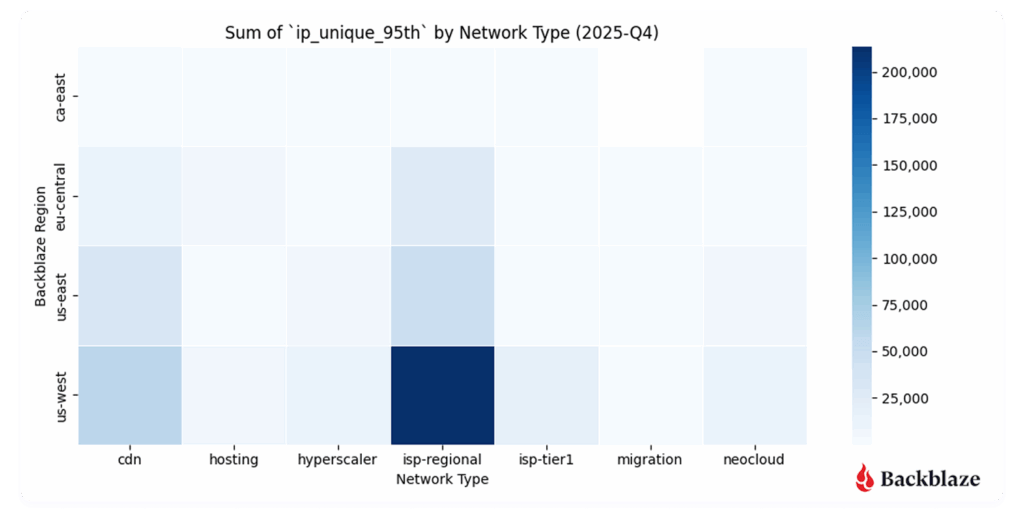
Heatmap #3: How many unique addresses do we interact with?

Uniqueness—measured by the number of distinct IP addresses per network type—adds another dimension to the story. Unsurprisingly, the quarter over quarter heatmap looks almost identical. This is expected with our US-West region being the most mature and serving a large amount of ISP Regional consumers and is a good sanity check on our dataset.

  • US-West shows the highest overall uniqueness, driven by its larger number of data centers and mix of workloads.
  • Neocloud traffic, by contrast, tends to involve fewer, more persistent endpoints, consistent with AI pipelines that rely on stable, long-standing connections between storage and compute. 

This is where we can clearly see those AI networking elephant flows showing up in the data.

Summary: Seasonal change in traffic flows

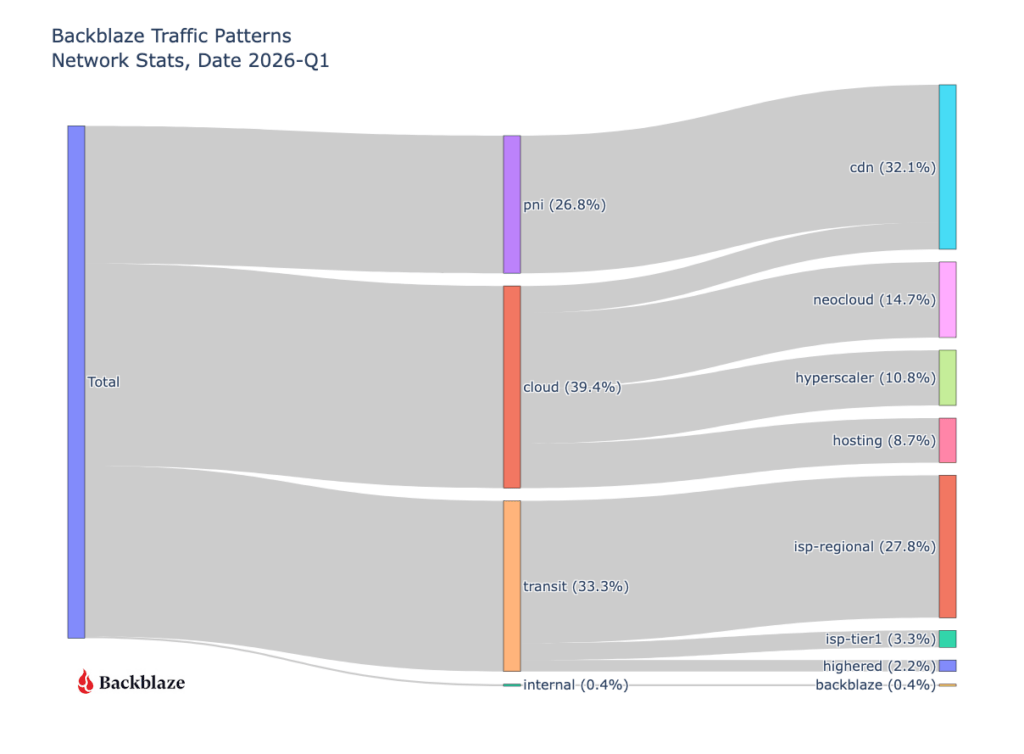
With a lull in bits transferred as noted in our top level graph, we can see what other networks by percentage took over. CDN traffic increased from around 20% to 32% of our total traffic, localized ISP regional traffic also increased 21.5% to 27.8%. Neocloud and hyperscaler traffic reduced from 36.4% in Q4 2025 to 25.5% in Q1 2026. 

Quarter over quarter data

We’re tracking our usual metrics here, and we gave you both this quarter and last quarter’s charts so you can easily spot potential trends.  

First let’s take a look at where all our traffic goes from a global perspective with an updated view of last quarter.

Next, let’s take a look at the geography of our network traffic. As we’ve already seen in previous heatmaps, data gravity is concentrating traffic into specific locations.

Where in the world is the neocloud?

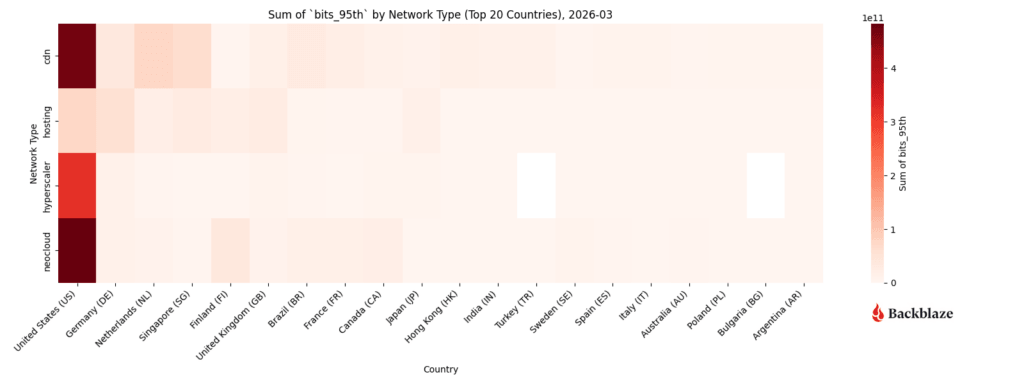
New for March 2026, we’ve added geographic information to our dataset, allowing us to take a look at the concentration of traffic based on network types. We’re taking a look into the following locational slices:

  1. Countries
  2. Countries excluding the United States
  3. U.S. states

Heatmap #1: What countries show the highest concentration of traffic by network type?

Neocloud, hyperscaler, and CDN traffic in our dataset all show high concentrations in the United States. Is this due to our US-West and US-East regions being the largest of our deployments or is it related to how certain traffic types are present in the emerging AI market? A quick search shows that the U.S. contains around 40-45% of all data centers globally, so it’s likely the sheer deployment size and scope of US sites aligns with what we’re seeing at the network level.

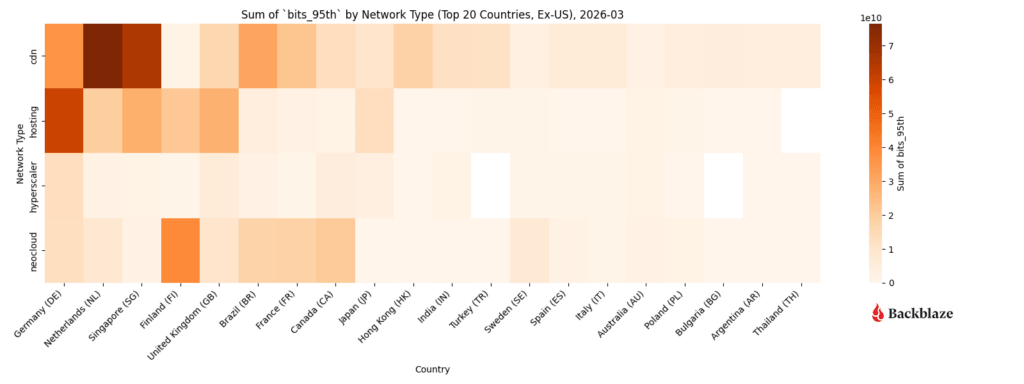
That said, excluding outliers can show us additional geographic trends, which leads to our next heatmap.

Heatmap #2: If we exclude the U.S., what countries show the highest concentration of traffic by network type?

Since the United States numbers highly skew the heatmap concentration, below is a heatmap without the US to give us better fidelity on ex-US datapoints. Interesting to note that we deliver a large amount of traffic to CDN entities in the Netherlands. This is due in part to our connectivity to AMS-IX (Amsterdam Internet Exchange). 

The network posture of Europe differs from the United States to where local IX networks are preferred over larger Tier1 ISP networks for transit (politically, cost, and preference wise). Second up is Singapore for CDN content and hosting activity in Germany. The next standout is a concentration of neocloud related activity in Finland, Brazil, France, and Canada.

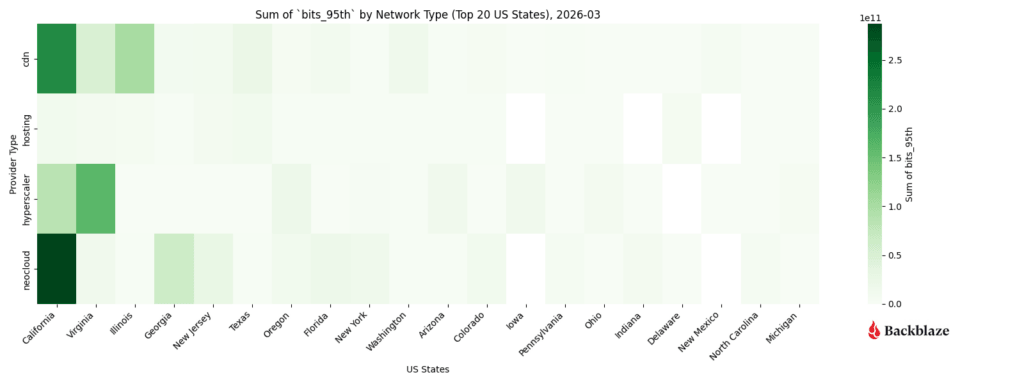
Heatmap #3: What U.S. States show the highest concentration of traffic by network type?

If we dive into just the U.S. States, we can see the heavily weighted concentration of neocloud traffic to and from California. Hyperscaler activity matching up with our expectations as California and Virginia (specifically the Ashburn and Reston corridor) have a high concentration of partner networks. CDN traffic for us concentrates more for Backblaze specifically since the US-West region is our largest cluster footprint and longest running sites, so naturally the data being served out of these sites is more long-lived content lifecycle wise.

These insights into data geography help us understand, plan, and modify our growth trajectory. I say “help,” because we’re also discovering that neocloud and hyperscaler activity is very bursty and has a high magnitude of traffic flow below. From a planning perspective, understanding whether those bursts translate to a higher baseline for increased demand—and how to support bursts when they happen—is a different conversation than the predictable network trends of years past. 

Neocloud and hyperscaler traffic vs predictive patterns

This quarter we’re sharing a deeper dive into the metrics associated with neocloud and hyperscalers over time. These two traffic types are driving innovation at Backblaze and are interesting to share to the larger industry. While CDN, hosting, and ISP regional traffic patterns are easy for us to model and account for as we manage our network infrastructure, neocloud and hyperscalers growth profiling are a challenge! As we said above, they are bursty and have a high magnitude (bits per associated IP address).

And, in the spirit of that conversation, we have several new views to share:

  • Neocloud and hyperscaler magnitude (bits per IP address) over time
  • Heatmaps over time
    • Neocloud
    • Hyperscaler
    • CDN
    • Hosting
    • ISP regional

Chart #1: What’s the magnitude of neocloud and hyperscaler traffic over time?

Matching our earlier charts, we saw a burst of activity from August to December of last year with a resurgence of high magnitude neocloud traffic in March of 2026.

Heatmap #1 and #2: How dynamic are neocloud and hyperscaler traffic patterns?

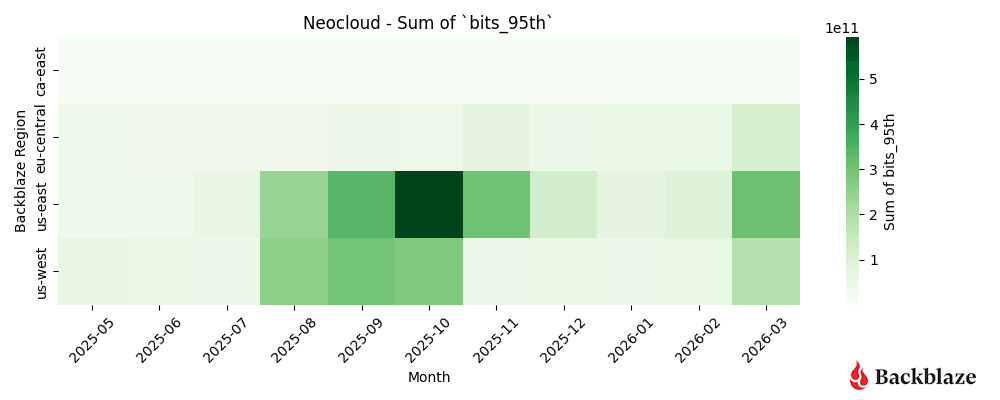
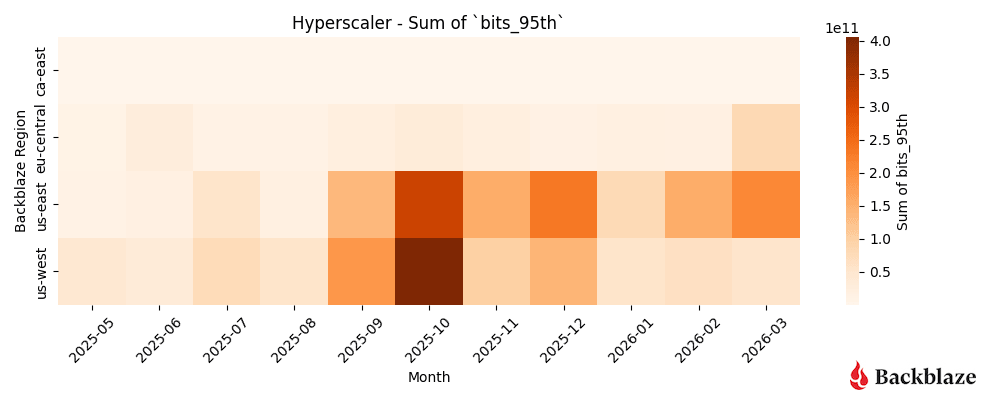
Neocloud and hyperscaler traffic patterns are the most impactful to our operations due to the magnitude of their data flows. Below is a more detailed look at these concentrations over time, with a burst of activity from August to November for Neoclouds, a quiet period over the winter months, and a pickup again in March. 

As expected our US-East region remains a hotspot of Neocloud related activity. One standout from this analysis is that the Neocloud activity in March is more spread out over our US-West, US-East, and EU-Central regions. It will be interesting to see if this spread grows or contracts over time.

Over the winter months, there was a noticeable decrease in activity for hyperscale related traffic, most notable in January, but when compared to neocloud traffic, the month-over-month traffic patterns remained strongly visible in our US-East region.

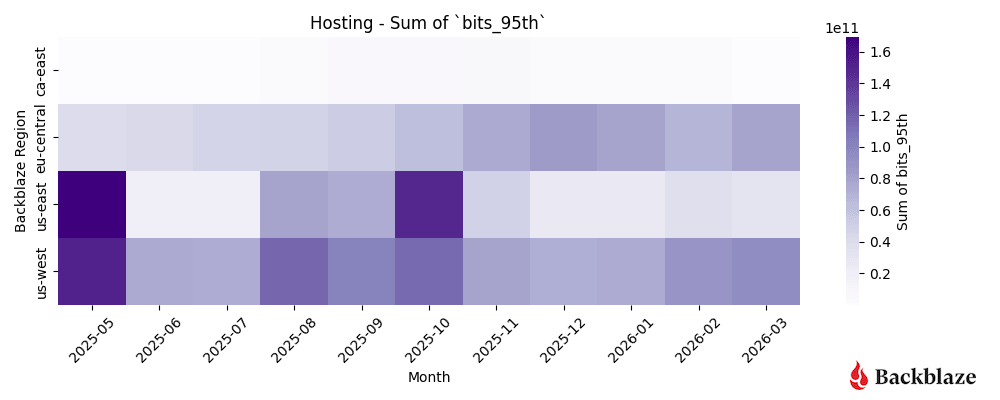
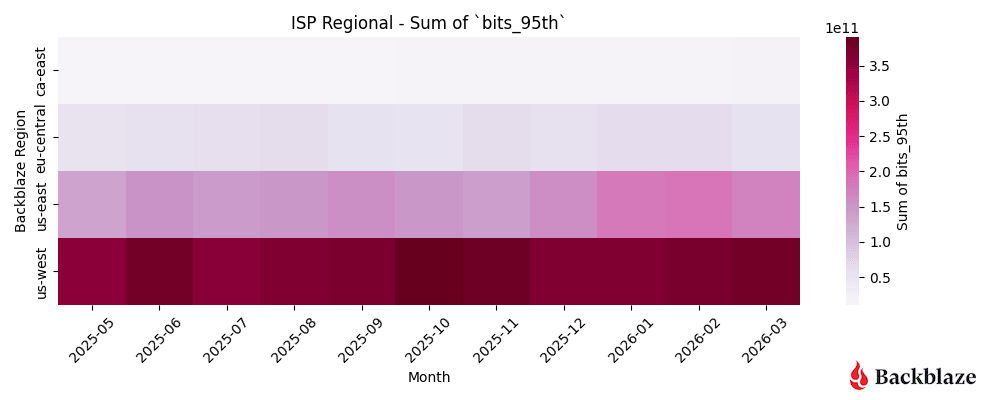
Heatmap #3, #4, and #5: How dynamic are CDN, hosting, and ISP regional traffic patterns?

We’re grouping CDN, hosting, and ISP regional types together because they represent a “steady-state” for us as network operators. These patterns are predictable, spread out over time, and generally do not change month-to-month. We do see visible bursts of traffic, like with a heavy blue tile for CDN in September and a few areas of hosting related traffic in May and October of 2025, but overall these are less impactful to our operations because the magnitude (bits per unique IP address) is lower—many sources are talking to many destinations, which as operators is easy to load balance.

The most striking example of this predictability is, unsurprisingly, ISP regional traffic. This represents your more consumer driven workflows and use cases.

Neocloud business cycle and geography

We can draw a conclusion from all these charts: neocloud and hyperscaler are both different traffic patterns and far more dynamic than CDN, hosting, and ISP regional traffic. For our Network Engineering group, this means we have two different stylistic approaches towards managing our network. 

First, when planning for the neocloud and hyperscaler traffic, our solutions entail adding large amounts of additional bandwidth in increments of 100G and often 400G ports to handle burst rates, ensuring that our inter-switch links inside our datacenter can also handle bursts of traffic, and reaching out to select partners to establish private network-to-network interface (PNI) connections where appropriate for zero-settlement transit. 

Our steady state growth patterns stem from CDN, hosting, and ISP regional traffic with easy to model growth curves. Looking over monthly numbers indicates a clear pattern for us, and that’s easy to plan for.

The last factor that we’re placing more emphasis on is the geographical location of our network interconnections. We’re seeing a high concentration of demand located in the United States, specifically in regions like California, Virginia, Illinois, and Georgia.

With more datapoints, we can clearly see the magnitude of the neocloud and hyperscaler transfers when compared to other network types. As above, it’s a bit early to claim concrete quarter over quarter patterns, but we’ll keep monitoring and updating the dataset. 

What’s next?

Anything specific you want to see? Let us know in the comments or reach out to the Network Stats team. Or, keep up-to-date with the latest technical content with our Developer Newsletter. 

The post Network Stats for Q1 2026: Neocloud Traffic Trends appeared first on Backblaze Blog | Cloud Storage & Cloud Backup
Backblaze B2 Neo Wins NAB Show 2026 Product of the Year

Post Syndicated from Laquie TN Campbell original https://www.backblaze.com/blog/backblaze-b2-neo-wins-nab-show-2026-product-of-the-year/

A decorative image showing the Backblaze logo and various digital elements.

NAB Show 2026 wrapped up last week in Las Vegas, and we left with something special in hand: the NAB Show Product of the Year Award in the Cloud Computing and Storage category—this time for Backblaze B2 Neo.

It’s a meaningful recognition, and one that reflects where we see the media and AI infrastructure market heading. Here’s a look at what the recognition means, and why B2 Neo matters.

What this recognition means

Winning the NAB Product of the Year Award reflects something we genuinely believe: that storage infrastructure is a foundational capability for modern media and AI platforms, not an afterthought or a separate vendor relationship to manage.

The NAB Show brings together the best of the media and entertainment industry, and having B2 Neo recognized in this context—among platforms solving real, production-scale problems across streaming, OTT, AI-driven media processing, and large-scale content delivery—is meaningful validation that the approach resonates.

B2 Neo launched in February 2026 and is already supporting production workloads including AI training pipelines, high-performance computing environments, and large-scale media delivery. The response from platform providers has reinforced what we know: organizations want to offer integrated, high-performance storage without building it from scratch, and they want the economics to make sense.

What is B2 Neo?

B2 Neo is a high-performance, S3-compatible cloud object storage solution purpose-built for platforms running data-intensive media and AI workloads. But describing it simply as “cloud storage” undersells the point.

The key distinction: B2 Neo is a white-label service. Rather than selling storage directly to end users, B2 Neo enables platform providers—like media workflow vendors—to offer fully integrated storage under their own brand. Partners launch their own storage service with custom endpoints, pricing, and user experiences, without having to build or operate the underlying infrastructure themselves.

The result is that platforms can go from “we don’t offer storage” to “we have a native, high-performance storage tier” in weeks rather than years, with none of the capital investment or engineering overhead that building it in-house would require.

Why it was built

The problem B2 Neo addresses has been growing for years, but it’s become acute as streaming, OTT, and AI-driven media workflows scale up.

Compute has gotten fast, distributed, and relatively affordable. GPU clusters, edge networks, and CDNs can all handle increasingly complex workloads. But storage has often lagged behind—fragmented across providers, expensive to move data in and out of, and either too costly or too operationally burdensome to build in-house.

The consequence is real: GPU clusters sit idle waiting on data. Streaming pipelines bottleneck on access speeds. Media organizations duplicate content across storage systems because no single layer integrates cleanly into the rest of the stack.

B2 Neo was designed to remove that bottleneck. It delivers up to 1Tbps of throughput to ensure that compute resources—GPU clusters, streaming systems, edge delivery networks—are never waiting on storage. It combines that performance with Backblaze’s 17+ years of operational experience at exabyte scale, and wraps it in an API-first architecture that plugs directly into partner platforms.

How it works

From a technical standpoint, B2 Neo delivers high aggregate throughput using cost-efficient, disk-based infrastructure with strategically deployed flash layers—a write-through cache design that captures the performance benefits of flash without the cost and scalability limitations that come with an all-flash architecture at the multi-petabyte scale that media and AI workloads require.

For workloads where throughput matters as much as latency—moving large video files, training AI models, serving content at scale—this approach is particularly effective. It allows platforms to maintain a centralized data repository and efficiently deliver data to compute providers, edge networks, and CDNs without duplicating data across storage systems.

API-driven provisioning lets partners programmatically create and manage storage accounts, permissions, and billing within their existing systems. Whether a partner is running an OTT platform, a media asset management system, or an AI training pipeline, B2 Neo integrates as a native extension of that environment rather than an external dependency to work around.

Included egress and free API calls round out the picture, eliminating the usage-based fees that typically make storage decisions financially complicated.

What’s next

This is a product that will keep evolving alongside the media and AI infrastructure landscape. We’re working closely with early partners to expand B2 Neo’s capabilities—performance, integration depth, provisioning flexibility—and we’ll have more to share as those conversations develop.

If you’re building or operating a platform that would benefit from embedded, high-performance storage, we’d love to talk. Reach out to our team to learn more about what a B2 Neo partnership looks like.

See you at NAB Show 2027!

The post Backblaze B2 Neo Wins NAB Show 2026 Product of the Year appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Meet the Partners Building the Future of Media Workflows with Backblaze

Post Syndicated from Laquie TN Campbell original https://www.backblaze.com/blog/meet-the-partners-building-the-future-of-media-workflows-with-backblaze/

A decorative image showing the Backblaze logo amidst film lights and cameras.

Modern media workflows don’t run on storage alone. They run on ecosystems—tightly integrated stacks of tools that ingest, process, analyze, move, review, and distribute content at scale. The companies we partner with aren’t just integrating with Backblaze; they’re building on it to solve real, specific problems that media teams face every day: archives that are impossible to search, file transfers that collapse over distance, review cycles that slow production to a crawl, compliance workflows that can’t keep up with library growth.

At NAB Show 2026, we’re bringing ten of those partners into booth N1259 to share what they’ve built. But the stories they’re telling aren’t just for Las Vegas—they’re for any media team trying to understand what a modern, cost-efficient, deeply integrated workflow actually looks like in practice.

Here’s a look at each partner, the problem they solve, and why it matters.

Imaginario AI: From Archive to Action

Presenter: Jose Puga, CEO and Co-Founder, Imaginario AI

Most video archives are passive. Content sits in storage, cataloged by someone who had time to do it years ago, effectively invisible to the people who could use it today. Imaginario AI flips that model.

Jose Puga’s session, “From Archive to Action: How AI Is Turning Your Video Library Into a Revenue Engine,” frames the shift from passive storage and cataloging to intelligent systems that actively surface, repurpose, and monetize content. The talk covers how marketing teams can accelerate campaigns, post-production teams can shortcut assembly, and compliance workflows can move from reactive to automated.

Imaginario is a multimodal video agentic platform that understands video in a human-like way—recognizing sounds, speech, and visual scenes without requiring time-based metadata. The platform is trusted by Warner Bros. Discovery, Sony Music, and Universal Pictures, and has won back-to-back IBC Best of Show honors in 2024 and 2025.

The Backblaze integration means content stays where it lives—no migration, no friction. As Jose puts it: “Backblaze provides our clients a scalable, reliable cloud layer that eliminates the friction of manual data transfers. Our native integration saves video teams dozens of hours by keeping content on Backblaze while unlocking high-speed AI analysis, retrieval, and repurposing in media and entertainment.”

Suite Studios: S3 Native File Streaming

Presenter: Jay Maxwell, Co-Founder & CPO, Suite Studios

Remote and distributed production teams have wrestled with the same problem for years: How do you collaborate on large media files when your team is spread across the globe? Suite’s answer is S3 Native File Streaming on Backblaze B2. The stack makes working with cloud object storage all-around easier, enabling teams to read and write data as standard objects without copying, syncing, or transferring.

Jay Maxwell’s session explores how global teams can instantly access and collaborate on large media files from anywhere—eliminating delays and accelerating production timelines. No syncing, no waiting, no workarounds. Just files that behave the way you need them to, wherever your team happens to be.

TwelveLabs: Unlocking Archive Value with Video AI

Presenter: Jordan Woods, Senior Solutions Architect, TwelveLabs

There’s a pattern across media organizations of all sizes: years of valuable archived content sitting effectively invisible because manual cataloging doesn’t scale. TwelveLabs makes that content searchable and monetizable.

Jordan Woods’ session, “Unlocking Archive Value with TwelveLabs Video Intelligence,” shows how pairing Backblaze’s cost-efficient storage with TwelveLabs’ video AI gives organizations a practical path to turn dormant archives into searchable, monetizable assets.

As Danny Nicolopoulos, Head of Strategic Partnerships at TwelveLabs, explains: “Media companies are sitting on years of valuable archived content that’s effectively invisible because manual cataloging doesn’t scale. Pairing Backblaze’s cost-efficient storage with TwelveLabs’ video AI gives organizations a practical path to turn those dormant archives into searchable, monetizable assets.”

Tillered: Full Speed Cloud Storage Over Any Distance

Presenters: Davey Goode, Founder & Stephen Ceci, Commercial Lead, Tillered

Physics is an undefeated opponent. Move data over long distances and throughput drops—no matter how fast your storage is or how much bandwidth you have. Tillered is built to remove that distance penalty.

The session, “Backblaze B2 Accelerate with Tillered: Full Speed Cloud Storage Over Any Distance,” demonstrates how the B2 Accelerate product brings Tillered’s acceleration technology to Backblaze B2, with transfers up to 34x faster as a result. No simulations—just live transfers with real results, showing what it looks like when enterprises can move data across any distance without adding bandwidth or changing workflows.

Davey Goode founded Tillered after repeatedly running into the same issue building large-scale connectivity infrastructure: No matter how much bandwidth was available, performance collapsed over distance. This session is the solution he built.

Telestream UP.Review: Decide Faster

Presenter: Sebastian Manemann, Senior Director of Product Management, Telestream

Capture, storage, and distribution have gotten faster. Review hasn’t kept up. Proxies, downloads, duplicated files—the approval workflow often undoes the speed gains made everywhere else in the pipeline.

Sebastian Manemann’s session, “Decide Faster: Real-Time Review, QC, and Delivery with Telestream UP.Review and Backblaze B2,” demos how Telestream UP.Review enables real-time, high-resolution playback and QC directly on media stored in Backblaze B2 without moving or duplicating files.

By keeping content in Backblaze as the central storage layer, teams can review instantly, validate quality, and move to delivery faster—all while maintaining a single source of truth across the workflow. As Sebastian frames it: “When you eliminate duplication and review directly from storage, you don’t just move faster—you operate smarter.”

Qencode + Sardius: A Multi-Vendor M&E Workflow in Practice

Presenters: Murad Mordukhay, CEO, Qencode, and Jason Shore & Ari Burt, Sardius Media

This one is different from the others—it’s not a product demo; it’s a case study. Sardius Media rebuilt their media pipeline around a race model: Multiple storage providers write in parallel, and the fastest result wins.

The session breaks down how Backblaze wins approximately 80% of those races, with Qencode orchestrating the encoding layer across the pipeline. It covers what the production data actually shows, and what Sardius would do differently if they were designing the workflow from scratch today.

Qencode uses machine learning to reduce file sizes by an average of 60% without sacrificing quality. Their CEO, Murad Mordukhay, sums up the partnership plainly: “The best partnerships are when two companies solve different halves of the same problem. Backblaze handles storage with the kind of reliability and transparency that perfectly aligns with how we think about transcoding. No surprises, no lock-in, just infrastructure that earns trust by performing every single day.”

HiScale: Orchestrating Media Across the Stack

Presenter: Christoph Jurkuhn, CEO, HiScale

Media workflows break down not just because of bad tools, but because of coordination failures between good ones. Files don’t sync. Teams duplicate work. Availability lags behind where content actually needs to be.

Christoph Jurkuhn’s session, “The Hidden Layer: Orchestrating Media Across the Stack with HiScale and Backblaze,” shows in a live demo how HiScale orchestrates media movement across distributed environments while Backblaze B2 provides the durable, scalable storage layer underneath. Files move, sync, and become available across teams and tools without delays, duplication, or manual intervention.

“Backblaze is built for straightforward, cost-efficient storage and HiScale builds on top of that to orchestrate and process your media. It’s a natural fit for modern media workflows.”

Iconik: Control Your Content

Presenter: Jeremy Strootman, Media Workflow Consultant, Iconik

At a certain scale, the problem isn’t creating content; it’s controlling it. Files get lost, search slows to a crawl, and archives become liabilities instead of assets.

Jeremy Strootman’s session, “Control Your Content: Turning Media Chaos into Operational Advantage,” demos how Iconik and Backblaze B2 give teams operational control over their media: making content instantly searchable, accessible, and reusable across the entire workflow.

With a foundational background in storage and archiving, Jeremy has spent over two decades helping content creators maximize efficiency and productivity across the entire media lifecycle, from ingest to archive. His perspective: “Backblaze gives us the scalable foundation; Iconik gives teams control over how that content is actually used.”

ToolsOnAir: Modern Broadcast Workflows on Backblaze

Presenter: Peter Steiner, Chief Business Officer, ToolsOnAir

Peter Steiner’s session, “Record, Store, Play: Modern Broadcast Workflows on Backblaze,” brings ToolsOnAir’s deep broadcast expertise to bear on what it looks like to build a complete ingest-to-playout workflow with Backblaze B2 as the storage foundation.

ToolsOnAir has been building Apple-based broadcast solutions for over a decade, with deployments across broadcast, ingest, and storage workflows worldwide. This session is for anyone running live or near-live operations who wants to understand what a modern, cloud-native broadcast stack actually looks like in practice.

Mixpeek: AI-Powered Media Compliance at Scale

Presenter: Ethan Steininger, Founder & CEO, Mixpeek

The final session tackles a problem that’s only growing: As video libraries scale into the billions of assets, compliance workflows built for smaller operations don’t hold.

Ethan Steininger’s session, “What You Miss Can Cost You: AI-Powered Media Compliance at Scale on Mixpeek and Backblaze B2,” shows how Mixpeek’s multimodal AI infrastructure platform transforms unstructured content—video, images, audio, and documents—into searchable, programmable assets through a unified API.

Before founding Mixpeek, Ethan led search at MongoDB, and today Mixpeek powers enterprise workflows across media, adtech, healthcare, and brand safety, with core technology spanning feature extraction, multimodal retrieval, and a custom-built distributed vector store engineered for billion-scale workloads.

The Bigger Picture

Ten companies, one through-line: storage that integrates cleanly across the entire media stack changes what’s possible. As I put it in my article for Post Perspective

What we are seeing is a broader realization that infrastructure decisions directly shape how teams build and operate. When pricing models penalize access or iteration, teams naturally limit how often they experiment or how much data they retain. That has a direct impact on product velocity and long-term value creation.

Backblaze didn’t have to react to this shift; it’s how we have always approached the market. Our cost model removes barriers like egress and transaction fees so teams can operate freely. That allows media organizations to focus on where value is actually created—whether that is content, audience engagement, or new AI-driven capabilities—while still maintaining craft excellence.

When your foundation is cost-efficient, S3-compatible, and built for reliability at scale, every tool in the ecosystem above it gets to do its best work. That’s what we mean when we talk about “building the future of media workflows”—not just that Backblaze stores your files, but that it enables the ecosystem built on top of it.

Join Us at NAB Show 2026

We’d love to show you around. Whether you want to catch one of the in-booth presentations, sit down for a workflow consultation, or talk through your specific storage and integration challenges, our team will be on-site all week.

Visit our booth N1259 or book a meeting at backblaze.com/nab2026.

NAB Show 2026 runs April 18–22 in Las Vegas, NV.

The post Meet the Partners Building the Future of Media Workflows with Backblaze appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Neoclouds Are Winning on Compute. Storage Shouldn’t Slow Them Down.

Post Syndicated from David Johnson original https://www.backblaze.com/blog/neoclouds-are-winning-on-compute-storage-shouldnt-slow-them-down/

A decorative image showing servers, the cloud, and drives.

Neoclouds are having a moment.

As demand for AI infrastructure keeps climbing, a new wave of providers is proving there’s real appetite for something other than the traditional hyperscaler model. They’re moving fast, specializing deeply, and building strong businesses around the layers that matter most to their customers: GPU access, high-performance compute, AI services, and developer experience.

That momentum is real, as is the next bottleneck. For many neoclouds, the challenge is no longer just how to deliver more compute. It’s how to deliver a more complete platform without taking on all the complexity of becoming a full-stack cloud provider. And that usually brings teams to the same question: Sshould we build our own storage layer?

Key points: Why should neoclouds care about specialized storage?

  • Neoclouds are capturing a major market opportunity by specializing in compute, AI, and high-performance infrastructure instead of trying to replicate the hyperscaler model. But without an independent, S3 compatible storage layer, many providers run into a split-stack problem: compute lives on the neocloud while data stays in a major cloud, bringing egress fees, friction, and architectural sprawl.
  • Teams that decide to build storage themselves often underestimate what that really means. Whether the path is open-source software like Ceph or purpose-built hardware, the result is often the same: Slower execution, more operational burden, and less focus on the product that actually differentiates the business.
  • The stronger strategy is to treat storage as a specialized tech stack layer and intentionally partner to solve the need, so internal teams can stay focused on compute, AI services, and customer experience.
  • Backblaze gives neoclouds an S3 compatible object storage backbone that can be integrated quickly, scaled immediately, and delivered without the overhead of building and operating storage from scratch.

The real neocloud opportunity is specialization

The shift toward neoclouds is really a shift toward specialization.

For years, the default assumption in cloud infrastructure was that the winning model looked like a hyperscaler: Build the entire stack, own every layer, and expand horizontally into as many services as possible. That model produced scale, but it also produced operational sprawl, complexity, and costs that many customers are increasingly motivated to avoid.

Neoclouds are succeeding because they’re taking the opposite path. Instead of trying to be everything to everyone, they’re building best-of-breed platforms around targeted workloads and high-value services. That’s especially true in AI, where performance, cost control, and speed matter more than a long menu of loosely related products.

But the closer a neocloud gets to becoming a full platform, the more pressure it faces to solve for storage.

The split-stack problem gets expensive

Without integrated object storage, customers often end up in a split-stack architecture. They run compute on a neocloud, but keep their data parked in a major cloud provider, which creates problems quickly.

For example: Large training datasets, model checkpoints, and output artifacts have to move across environments, costs become harder to predict, egress charges start to shape architecture decisions, and performance can suffer when storage and compute are no longer designed to work together.

At that point, storage becomes a core requirement for offering a platform that feels complete, efficient, and economically viable.

So teams ask the obvious question: should we build it ourselves?

Building storage usually means building a second company inside your company

This is where the conversation often gets framed too narrowly.

On paper, the decision can look straightforward: deploy open-source software such as Ceph, or design purpose-built hardware for tighter control over performance and economics.

In reality, both paths create the same strategic problem. They pull engineering focus away from your core platform and into a long-term storage business you never actually meant to start.

That matters because storage is not just infrastructure. It is an operating discipline. It comes with its own tuning, scaling, durability trade-offs, support burden, procurement risk, migration complexity, and day-two operational entropy.

Once you build it, you own all of it.

The software trap: Ceph is open source, not low overhead

Ceph is often the default option for teams exploring S3 compatible storage because it appears flexible, proven, and relatively accessible on commodity hardware.

And to be clear, Ceph can be powerful. But there’s a big difference between deploying Ceph and running it well at scale.

In production, Ceph demands specialized expertise. Teams have to manage CRUSH maps, OSD tuning, replication behavior, rebalancing events, and the network impact that comes with those changes. Those are not occasional tasks. They are part of the ongoing operational load.

That burden grows as environments get larger and more performance-sensitive.

For AI and high-performance compute use cases, generic Ceph deployments can also become throughput bottlenecks. When storage ceilings start constraining training jobs or data-intensive workflows, the problem is no longer confined to the storage team. It starts affecting the value of your core compute offering.

And migration is rarely simple. Because data is distributed across the cluster in ways that are optimized for internal resilience, moving out of a Ceph environment can become a resource-heavy extraction exercise that introduces risk to live workloads.

So while Ceph may reduce license costs up front, it can create a much more expensive operational reality over time.

The hardware trap: more control, more rigidity

For some neocloud teams, custom storage hardware feels like the more strategic answer.

The logic is easy to understand: if storage is critical, why not optimize the hardware and software stack together and get more predictable performance?

The issue is that custom storage hardware rarely stays clean and predictable for long.

Supply chains change. Drive capacities shift. Components become harder to source consistently. Architectures designed around one hardware profile suddenly have to absorb another. This dynamic can leave teams paying for density they can’t fully use or reworking systems to accommodate equipment that wasn’t part of the original plan.

Durability management adds another layer of complexity. As systems age, parity strategies and erasure coding decisions may need to change to maintain reliability. That can reduce usable capacity, increase cost per terabyte, and trigger compute-intensive re-encoding processes at exactly the wrong time.

Then there’s the networking layer. At scale, object storage is not just disks and nodes. It also depends on a traffic management architecture capable of handling massive ingress and egress flows without introducing opaque failure points. Whether you build around open source components or buy expensive hardware appliances, you’re signing up for another category of highly specialized infrastructure work.

And all of that comes with a capital model that is harder to unwind. Hardware investments lock teams into depreciation cycles and planning assumptions that may not match where the market is headed next.

The strategic shift: own differentiation, not every layer

The most important shift here is not technical. It’s organizational.

At a certain point, the storage question becomes a question of where your best people should spend their time.

Should your engineers be tuning replication policies, planning hardware refreshes, and troubleshooting storage network behavior?

Or should they be improving the platform features your customers actually choose you for?

For most neoclouds, the answer is clear.

Their advantage comes from how well they deliver compute, how quickly they adapt to AI demand, how smooth their developer experience feels, and how effectively they help customers run modern workloads. That is where focus compounds. That is where differentiation lives.

Storage matters enormously, but that does not mean it has to be built in-house.

Storage works better as a specialized utility

The neocloud ecosystem works best when providers can connect to open, specialized layers instead of rebuilding the entire stack themselves.

When storage is treated as a utility rather than an internal R&D project, teams can move faster and stay aligned with what the business actually needs. They avoid procurement cycles, reduce operational overhead, and eliminate a category of complexity that would otherwise keep expanding over time.

Equally importantly, they can offer customers a more complete and coherent platform without forcing data to remain trapped in legacy cloud environments.

How Backblaze helps neoclouds move faster

Backblaze gives neoclouds an independent, S3-compatible object storage backbone that can plug into existing compute, AI, and container workflows without requiring a storage buildout from scratch.

That means teams can:

  • Integrate with existing tooling: Use a drop-in, API-compatible storage layer that works with existing workflows, SDKs, CLIs, and infrastructure tools.
  • Reduce operational burden: Offload the complexity of durability engineering, bit-rot protection, fleet management, and storage operations.
  • Avoid punitive egress economics: In Backblaze-powered and colocated partner environments, move data between compute and storage without the cost friction that often comes with major cloud architectures.
  • Scale immediately: Go from terabytes to exabytes without waiting on hardware procurement, deployment schedules, or expansion projects.
  • Keep teams focused: Direct engineering effort toward the product roadmap instead of a second internal storage program.

Backblaze also brings the underlying scale and performance neoclouds need to support modern AI and data-intensive workloads, including up to 1Tbps aggregate throughput, 11 nines of annual durability, a 99.9% uptime SLA, and enterprise security and compliance capabilities.

Build what matters

Neoclouds are winning because they know where to specialize.

That focus is their strength. It is also their opportunity.

The fastest path to a stronger platform is not to recreate every layer of the cloud stack. It is to build the parts that make your business distinct, then connect them to the right partners for the rest.

Storage is too important to ignore, but it is also too easy to underestimate.

If you want to move faster, serve customers better, and keep your roadmap centered on what makes your platform valuable, don’t turn storage into a distraction.

Build what matters. Let Backblaze handle the storage.Interested in learning how Backblaze supports neocloud platforms? Explore B2 Neo or talk with our team about building a more open, AI-ready storage architecture.

The post Neoclouds Are Winning on Compute. Storage Shouldn’t Slow Them Down. appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

A Developer’s Guide to Migrating Multimodal AI Training Data (and Putting It to Work) with Pixeltable

Post Syndicated from Maddie Presland original https://www.backblaze.com/blog/a-developers-guide-to-migrating-multimodal-ai-training-data-and-putting-it-to-work-with-pixeltable/

A decorative image showing gears and a cloud.

Today’s AI models consume much more than text—everything from product images to video from surveillance feeds to audio from customer calls to metadata spread across an ever-expanding set of systems. These multimodal datasets drive everything from computer vision pipelines to customer service automation. But as they scale, the underlying infrastructure starts to creak.

Costs can become unpredictable. Data fragments across S3 buckets, HDFS clusters, and local drives. Maintaining cross-modal alignment, i.e. ensuring that media files stay linked to their labels, embeddings, and annotations, becomes a bottleneck that slows development to a crawl.This article outlines a practical path forward: how to migrate multimodal training data using proven open-source tools, and how Pixeltable helps unify and index that data for training once it lands in Backblaze B2.

Moving multimodal training data: Practical open source software (OSS) tools that do the heavy lifting

Before you can train on consolidated data, you need to get it all into one place. These three open-source tools handle the migration work, each addressing a different piece of the puzzle.

Apache NiFi for moving large media reliably

When your dataset includes terabytes of video files, thousands of high-resolution images, or large binary assets like LIDAR scans, you need something more robust than a shell script. Apache NiFi is purpose-built for moving large media files at scale.

NiFi provides:

  • Flow control and retry logic that handle network interruptions gracefully, which is essential when transferring terabytes of data over hours or days.
  • Data provenance tracking that records exactly which files moved where and when, making it possible to debug issues without guessing.
  • A visual workflow designer that lets you build and monitor data flows without writing custom code.

For multimodal datasets where media volume dominates, NiFi ensures files arrive intact and trackable. Check the Apache NiFi User Guide to get started with building your first data flow.

Airbyte for syncing structured and semi-structured metadata

Media files are only half the story. Annotations, labels, captions, transcripts, and database records provide the context that makes raw media useful for training. Airbyte excels at moving this structured and semi-structured metadata.

Airbyte handles:

  • Schema consistency when pulling metadata from multiple sources, ensuring annotation formats don’t drift between your labeling platform, your CRM, and your feature store.
  • Incremental syncs that only transfer changed records, avoiding unnecessary data movement as your datasets grow.
  • Multiple data systems via a broad catalog of connectors for databases, SaaS platforms, file formats, and cloud storage services.

Unlike NiFi, which focuses on raw file movement, Airbyte understands data schemas and transformations. Use it to keep your metadata in sync across systems. The Airbyte documentation provides setup guides for most common data sources.

lakeFS for versioning for reproducible training

After moving media via NiFi and metadata via Airbyte, you need a way to snapshot the entire dataset so you can reproduce training runs six months later. lakeFS brings Git-like version control to object storage.

lakeFS enables:

  • Branching and snapshots of entire datasets without copying data. You can create a branch, run an experiment, and merge or discard the results.
  • Atomic commits that ensure media, metadata, and derived features stay aligned as your corpus evolves.
  • Zero-copy clones that let multiple teams work on isolated versions of production data without storage overhead.

lakeFS acts as a version control layer on top of storage like Backblaze B2, tracking changes without duplicating objects. When a training run produces a new model, you can tag the exact dataset version that went into it. The lakeFS quickstart guide walks through creating your first repository and branch.

After migration, the hard part begins: Making the dataset usable

Moving data into object storage solves logistics, not usability. Even in B2, your media files, labels, and derived features remain scattered—images in one prefix, annotations in another, embeddings in a third. Training code becomes a tangle of custom loaders that stitch everything together, break when datasets change, and consume more engineering time than model tuning.

Where Pixeltable fits

Pixeltable provides the missing layer between migrated storage and training-ready data. It’s a declarative data infrastructure specifically designed for multimodal AI applications.

Here’s what Pixeltable does:

  • Unifies media and metadata into a single table interface: images, video frames, audio clips, and their associated labels, embeddings, and annotations live in one queryable structure.
  • Stores computed results automatically. Run OCR on documents, generate CLIP embeddings for images, or extract audio transcripts once, and Pixeltable caches the results for reuse.
  • References Backblaze B2 objects directly without copying data. Files stay in Backblaze B2, and Pixeltable maintains pointers and metadata in a local Postgres instance. Pixeltable automatically caches the files locally on access, and can write media files back to B2 (see our project for examples: https://github.com/backblaze-b2-samples/b2-pixeltable-multimodal-data).
  • Supports built-in transforms like embedding generation, image captioning, and OCR with lazy evaluation. Define transformations once, and they run incrementally as new data arrives.

Instead of maintaining custom loaders and indexing scripts, you define a schema once. Pixeltable handles orchestration, caching, and queries. The result is a training dataset you can slice, filter, and feed directly into PyTorch DataLoaders or Hugging Face Datasets.

Check the Pixeltable documentation to see how tables, computed columns, and queries work in practice.

A practical end-to-end workflow

Here’s how these tools fit together in a real-world pipeline:

1. Move media via NiFi → Backblaze B2

Set up an Apache NiFi flow to transfer images, video files, or other large binaries from your current storage (on-premise NAS, another cloud provider, or local drives) to a Backblaze B2 bucket. Configure retry logic and provenance tracking so you can verify every file arrived.

Use NiFi processors like GetFile, PutS3Object, and RouteOnAttribute to handle file movement and error routing. The Backblaze B2 Cloud Storage S3-compatible API works seamlessly with NiFi’s S3 processors.

2. Sync metadata via Airbyte

Configure Airbyte to pull annotations, labels, captions, and database records from your labeling tool, feature store, or other sources. Set up connections to sync metadata incrementally as it changes. If annotations live in Postgres and captions come from a cloud-based labeling platform, Airbyte normalizes both into a consistent schema in Backblaze B2 or a dedicated metadata store.

3. Create a lakeFS branch to snapshot the dataset

Initialize a lakeFS repository pointing to your Backblaze B2 bucket. Create a branch to isolate this version of the dataset. If something goes wrong during training, you can roll back or compare versions. Use the lakeFS CLI or Python client to create branches and commits programmatically.

4. Define a Pixeltable schema referencing B2 objects + synced metadata

In Pixeltable, create a table with columns for image paths (pointing to Backblaze B2), labels, captions, and any other metadata fields. Import your data so each row represents one training example: one image, its label, its caption, and any associated metadata.Pixeltable doesn’t copy image files—it stores references and metadata, automatically caching the files locally on access. The images stay in Backblaze. The Pixeltable Tables guide explains how to create tables with multimodal column types and import data from external sources.

5. Run transforms (embeddings, captions, OCR) inside Pixeltable

Define computed columns for embeddings, captions, or OCR results. Pixeltable’s computed columns run transformations lazily as data is queried or when you explicitly trigger computation.

For example, you can add CLIP embeddings using Pixeltable’s built-in Hugging Face integration, or generate AI captions using OpenAI’s vision API. Once defined, these columns compute incrementally—new images trigger automatic processing without reprocessing the entire dataset.

The Pixeltable API reference documents all available functions for common operations like embedding generation, image processing, and text analysis.

6. Query or filter the unified dataset

Use Pixeltable’s query interface to filter, sort, and slice your data. For example, find all images labeled “cat” with embeddings similar to a reference image. Or extract rows where captions mention “outdoor” and timestamps fall within a specific range.

7. Feed batches directly into PyTorch/Hugging Face

Export data from Pixeltable into PyTorch DataLoaders or Hugging Face Datasets format for training. Pixeltable handles batching, shuffling, and data access so your training loop stays clean.

The Pixeltable documentation covers various export formats and integrations with popular ML frameworks, allowing you to avoid intermediate export steps and maintain a streamlined workflow from data preparation to model training.

From fragmented storage to production-ready training data

Multimodal AI datasets don’t have to be a maintenance nightmare. By chaining together proven open-source tools—NiFi and Airbyte for migration, lakeFS for versioning, and Pixeltable for unified access—you can turn scattered files and metadata into queryable training assets.

Once data lands in Backblaze B2, this stack eliminates the custom glue code, brittle loaders, and alignment issues that typically slow down training workflows. Your team gets reproducible datasets, clean interfaces, and more time for model development instead of infrastructure firefighting.

Ready to get started? Check out the Backblaze B2 documentation to set up your object storage, and explore Pixeltable’s examples to see multimodal workflows in action.

The post A Developer’s Guide to Migrating Multimodal AI Training Data (and Putting It to Work) with Pixeltable appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

How Workers VPC Services connects to your regional private networks from anywhere in the world

Post Syndicated from Thomas Gauvin original https://blog.cloudflare.com/workers-vpc-open-beta/

In April, we shared our vision for a global virtual private cloud on Cloudflare, a way to unlock your applications from regionally constrained clouds and on-premise networks, enabling you to build truly cross-cloud applications.

Today, we’re announcing the first milestone of our Workers VPC initiative: VPC Services. VPC Services allow you to connect to your APIs, containers, virtual machines, serverless functions, databases and other services in regional private networks via Cloudflare Tunnels from your Workers running anywhere in the world. 

Once you set up a Tunnel in your desired network, you can register each service that you want to expose to Workers by configuring its host or IP address. Then, you can access the VPC Service as you would any other Workers service binding — Cloudflare’s network will automatically route to the VPC Service over Cloudflare’s network, regardless of where your Worker is executing:

export default {
  async fetch(request, env, ctx) {
    // Perform application logic in Workers here	

    // Call an external API running in a ECS in AWS when needed using the binding
    const response = await env.AWS_VPC_ECS_API.fetch("http://internal-host.com");

    // Additional application logic in Workers
    return new Response();
  },
};

Workers VPC is now available to everyone using Workers, at no additional cost during the beta, as is Cloudflare Tunnels. Try it out now. And read on to learn more about how it works under the hood.

Connecting the networks you trust, securely

Your applications span multiple networks, whether they are on-premise or in external clouds. But it’s been difficult to connect from Workers to your APIs and databases locked behind private networks. 

We have previously described how traditional virtual private clouds and networks entrench you into traditional clouds. While they provide you with workload isolation and security, traditional virtual private clouds make it difficult to build across clouds, access your own applications, and choose the right technology for your stack.

A significant part of the cloud lock-in is the inherent complexity of building secure, distributed workloads. VPC peering requires you to configure routing tables, security groups and network access-control lists, since it relies on networking across clouds to ensure connectivity. In many organizations, this means weeks of discussions and many teams involved to get approvals. This lock-in is also reflected in the solutions invented to wrangle this complexity: Each cloud provider has their own bespoke version of a “Private Link” to facilitate cross-network connectivity, further restricting you to that cloud and the vendors that have integrated with it.

With Workers VPC, we’re simplifying that dramatically. You set up your Cloudflare Tunnel once, with the necessary permissions to access your private network. Then, you can configure Workers VPC Services, with the tunnel and hostname (or IP address and port) of the service you want to expose to Workers. Any request made to that VPC Service will use this configuration to route to the given service within the network.

{
  "type": "http",
  "name": "vpc-service-name",
  "http_port": 80,
  "https_port": 443,
  "host": {
    "hostname": "internally-resolvable-hostname.com",
    "resolver_network": {
      "tunnel_id": "0191dce4-9ab4-7fce-b660-8e5dec5172da"
    }
  }
}

This ensures that, once represented as a Workers VPC Service, a service in your private network is secured in the same way other Cloudflare bindings are, using the Workers binding model. Let’s take a look at a simple VPC Service binding example:

{
  "name": "WORKER-NAME",
  "main": "./src/index.js",
  "vpc_services": [
    {
      "binding": "AWS_VPC2_ECS_API",
      "service_id": "5634563546"
    }
  ]
}

Like other Workers bindings, when you deploy a Worker project that tries to connect to a VPC Service, the access permissions are verified at deploy time to ensure that the Worker has access to the service in question. And once deployed, the Worker can use the VPC Service binding to make requests to that VPC Service — and only that service within the network. 

That’s significant: Instead of exposing the entire network to the Worker, only the specific VPC Service can be accessed by the Worker. This access is verified at deploy time to provide a more explicit and transparent service access control than traditional networks and access-control lists do.

This is a key factor in the design of Workers bindings: de facto security with simpler management and making Workers immune to Server-Side Request Forgery (SSRF) attacks. We’ve gone deep on the binding security model in the past, and it becomes that much more critical when accessing your private networks. 

Notably, the binding model is also important when considering what Workers are: scripts running on Cloudflare’s global network. They are not, in contrast to traditional clouds, individual machines with IP addresses, and do not exist within networks. Bindings provide secure access to other resources within your Cloudflare account – and the same applies to Workers VPC Services.

A peek under the hood

So how do VPC Services and their bindings route network requests from Workers anywhere on Cloudflare’s global network to regional networks using tunnels? Let’s look at the lifecycle of a sample HTTP Request made from a VPC Service’s dedicated fetch() request represented here:


It all starts in the Worker code, where the .fetch() function of the desired VPC Service is called with a standard JavaScript Request (as represented with Step 1). The Workers runtime will use a Cap’n Proto remote-procedure-call to send the original HTTP request alongside additional context, as it does for many other Workers bindings. 

The Binding Worker of the VPC Service System receives the HTTP request along with the binding context, in this case, the Service ID of the VPC Service being invoked. The Binding Worker will proxy this information to the Iris Service within an HTTP CONNECT connection, a standard pattern across Cloudflare’s bindings to place connection logic to Cloudflare’s edge services within Worker code rather than the Workers runtime itself (Step 2). 

The Iris Service is the main service for Workers VPC. Its responsibility is to accept requests for a VPC Service and route them to the network in which your VPC Service is located. It does this by integrating with Apollo, an internal service of Cloudflare One. Apollo provides a unified interface that abstracts away the complexity of securely connecting to networks and tunnels, across various layers of networking

To integrate with Apollo, Iris must complete two tasks. First, Iris will parse the VPC Service ID from the metadata and fetch the information of the tunnel associated with it from our configuration store. This includes the tunnel ID and type from the configuration store (Step 3), which is the information that Iris needs to send the original requests to the right tunnel.

Second, Iris will create the UDP datagrams containing DNS questions for the A and AAAA records of the VPC Service’s hostname. These datagrams will be sent first, via Apollo. Once DNS resolution is completed, the original request is sent along, with the resolved IP address and port (Step 4). That means that steps 4 through 7 happen in sequence twice for the first request: once for DNS resolution and a second time for the original HTTP Request. Subsequent requests benefit from Iris’ caching of DNS resolution information, minimizing request latency.

In Step 5, Apollo receives the metadata of the Cloudflare Tunnel that needs to be accessed, along with the DNS resolution UDP datagrams or the HTTP Request TCP packets. Using the tunnel ID, it determines which datacenter is connected to the Cloudflare Tunnel. This datacenter is in a region close to the Cloudflare Tunnel, and as such, Apollo will route the DNS resolution messages and the Original Request to the Tunnel Connector Service running in that datacenter (Step 5).


The Tunnel Connector Service is responsible for providing access to the Cloudflare Tunnel to the rest of Cloudflare’s network. It will relay the DNS resolution questions, and subsequently the original request to the tunnel over the QUIC protocol (Step 6).

Finally, the Cloudflare Tunnel will send the DNS resolution questions to the DNS resolver of the network it belongs to. It will then send the original HTTP Request from its own IP address to the destination IP and port (Step 7). The results of the request are then relayed all the way back to the original Worker, from the datacenter closest to the tunnel all the way to the original Cloudflare datacenter executing the Worker request.

What VPC Service allows you to build

This unlocks a whole new tranche of applications you can build on Cloudflare. For years, Workers have excelled at the edge, but they’ve largely been kept “outside” your core infrastructure. They could only call public endpoints, limiting their ability to interact with the most critical parts of your stack—like a private accounts API or an internal inventory database. Now, with VPC Services, Workers can securely access those private APIs, databases, and services, fundamentally changing what’s possible.


This immediately enables true cross-cloud applications that span Cloudflare Workers and any other cloud like AWS, GCP or Azure. We’ve seen many customers adopt this pattern over the course of our private beta, establishing private connectivity between their external clouds and Cloudflare Workers. We’ve even done so ourselves, connecting our Workers to Kubernetes services in our core datacenters to power the control plane APIs for many of our services. Now, you can build the same powerful, distributed architectures, using Workers for global scale while keeping stateful backends in the network you already trust.

It also means you can connect to your on-premise networks from Workers, allowing you to modernize legacy applications with the performance and infinite scale of Workers. More interesting still are some emerging use cases for developer workflows. We’ve seen developers run cloudflared on their laptops to connect a deployed Worker back to their local machine for real-time debugging. The full flexibility of Cloudflare Tunnels is now a programmable primitive accessible directly from your Worker, opening up a world of possibilities.

The path ahead of us

VPC Services is the first milestone within the larger Workers VPC initiative, but we’re just getting started. Our goal is to make connecting to any service and any network, anywhere in the world, a seamless part of the Workers experience. Here’s what we’re working on next:

Deeper network integration. Starting with Cloudflare Tunnels was a deliberate choice. It’s a highly available, flexible, and familiar solution, making it the perfect foundation to build upon. To provide more options for enterprise networking, we’re going to be adding support for standard IPsec tunnels, Cloudflare Network Interconnect (CNI), and AWS Transit Gateway, giving you and your teams more choices and potential optimizations. Crucially, these connections will also become truly bidirectional, allowing your private services to initiate connections back to Cloudflare resources such as pushing events to Queues or fetching from R2.

Expanded protocol and service support. The next step beyond HTTP is enabling access to TCP services. This will first be achieved by integrating with Hyperdrive. We’re evolving the previous Hyperdrive support for private databases to be simplified with VPC Services configuration, avoiding the need to add Cloudflare Access and manage security tokens. This creates a more native experience, complete with Hyperdrive’s powerful connection pooling. Following this, we will add broader support for raw TCP connections, unlocking direct connectivity to services like Redis caches and message queues from Workers ‘connect()’.

Ecosystem compatibility. We want to make connecting to a private service feel as natural as connecting to a public one. To do so, we will be providing a unique autogenerated hostname for each Workers VPC Service, similar to Hyperdrive’s connection strings. This will make it easier to use Workers VPC with existing libraries and object–relational mapping libraries that may require a hostname (e.g., in a global ‘fetch()’ call or a MongoDB connection string). Workers VPC Service hostname will automatically resolve and route to the correct VPC Service, just as the ‘fetch()’ command does.

Get started with Workers VPC

We’re excited to release Workers VPC Services into open beta today. We’ve spent months building out and testing our first milestone for Workers to private network access. And we’ve refined it further based on feedback from both internal teams and customers during the closed beta. 

Now, we’re looking forward to enabling everyone to build cross-cloud apps on Workers with Workers VPC, available for free during the open beta. With Workers VPC, you can bring your apps on private networks to region Earth, closer to your users and available to Workers across the globe.

Get started with Workers VPC Services for free now.

Architecting Your AI Data Pipeline Using B2 Overdrive

Post Syndicated from Jeronimo De Leon original https://www.backblaze.com/blog/architecting-your-ai-data-pipeline-using-b2-overdrive/

A decorative image showing cloud storage and AI icons.

When you think about cloud infrastructure for AI, you immediately think of GPUs and other high-performance compute resources, and how your cloud architecture should be optimized to make the most of these expensive compute plans. But compute isn’t the only cloud product category you need to monitor to both scale your application and maintain a sustainable cloud infrastructure budget.

What ultimately fuels AI? Data—lots and lots of data. As part of a healthy AI pipeline, several versions of the same dataset need to be stored in a centralized repository, or multiple repositories if your strategy requires splitting data into cold vs. hot storage to reduce storage costs. For text-based LLMs, storage costs are minimal compared to compute resources. But as AI innovation increasingly relies on video and other media, both the base storage cost and data retrieval fees can make cloud bills spiral out of control.

In this blog, we’re taking a look at the AI data pipeline, where object storage sits in each stage, and how leveraging both Backblaze B2 and B2 Overdrive helps both increase performance and reduce costs for AI applications.

AI data pipeline stages

There are five key AI data pipeline stages where data retrieval and overall performance is critical—and this performance starts with your designated data storage backend.

  • Data ingest and active archive: Data is gathered from multiple designated sources (including APIs, internet of things (IoT) sensors, relational databases, etc.) and ingested into a centralized repository or multiple repositories.
  • Data processing: The raw data is transformed and enriched based on the model’s data parameters. This can range from relatively simple text cleanup to adding annotations and metadata. Feature engineering is performed to extract or construct meaningful attributes. All data is then converted into numerical representations (e.g., embeddings, vectors) suitable for model training and inference.
  • Model experimentation and training: Processed data is used to train models by learning underlying patterns. Iterative experiments in a test environment evaluate, tune, and improve model performance and accuracy.
  • Model deployment and inference: New data is prepared in the same way as during training and sent to the deployed model to generate predictions, support decision-making, and deliver personalized outputs.
  • Monitoring: Continuous monitoring tracks model performance, detects data drift, and flags potential bias, ensuring the model remains accurate and reliable over time.

Keep in mind that data ingestion and processing isn’t always sequential, such as when data is collected and ingested, but corruption is detected during processing. Ideally, your pipeline is configured with validation gates so that corrupt data is identified and handled before proceeding to downstream steps like testing, training, and production deployment.

When using cloud object storage as your data repository, one factor of selecting a plan (like cold versus hot storage) is the specific type of data ingestion that’s being utilized based on both the data source and AI model’s specific needs.

  • Batch ingestion is better suited for mid to lower performance storage, as this is typically used for historical datasets or a set schedule of pre-determined data updates, such as jobs pulling from relational databases or CSV uploads once a day or once per week.
  • Streaming ingestion is well-suited for hot storage to support a continuous stream of real-time (or near-real-time) data processing, such as from social media feeds and high-volume e-commerce AI helper agents.
  • Hybrid ingestion uses a combination of batch and streaming ingestion to handle both historical and real-time data requirements for AI models.

Where does cloud object storage sit in the AI data pipeline?

Everywhere. All scalable data pipelines lead to object storage.

Why? Data ingestion and active archive are the major areas where object storage fulfills an important purpose. When training AI models, especially in production, data scalability for multiple and diverse data types is a hard requirement. But object storage plays a key role in the other pipeline stages:

  • Data processing: Stores versioned outputs from data labeling, feature engineering, and cleaning processes.
  • Model experimentation and training: Provides high-throughput access to training datasets and stores model checkpoints.
  • Model deployment and inference: Stores serialized model artifacts with API-based retrieval for serving predictions at scale.
  • Monitoring: Stores synthetic outputs from generative models, logs, feedback, and performance metrics for analysis and reuse.

For both AI data performance and cost optimization, selecting an object storage product or tier is far from one-size-fits-all. You can strategically allocate your data to B2 Cloud Storage or B2 Overdrive, with your most essential model data stored in B2 Overdrive.  Here’s a high-level diagram of what Backblaze B2 product to use for each stage, including examples of the data stored at each stage.

Learn more at Ai4 in August

Want to learn more? Backblaze is heading to Las Vegas for Ai4 August 11–13! In addition to booking a meeting to speak with our storage experts and stopping by our booth to pick up some swag, I’m excited to talk more about the AI data pipeline during my talk. If you’re attending Ai4, add The AI Pipeline Starts with Storage: Architecting Scalable Data Foundations to your conference agenda.

Can’t attend live in Vegas? Reach out to our Sales team to talk about your specific use case and how B2 Overdrive can help propel your data.

The post Architecting Your AI Data Pipeline Using B2 Overdrive appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

5 Ways to Use Event Notifications to Advance Your Media Better, Faster

Post Syndicated from Jeremy Milk original https://www.backblaze.com/blog/5-ways-to-use-event-notifications-to-advance-your-media-better-faster/

A decorative image showing a cloud with digital lines and media icons.

In the hurry-up-and-wait world of media production, anything you can do to speed through the hurry-ups and avoid or shorten the waits is not just a gift—it’s an advantage that can mean happier team members, delighted clients and fans, and more revenue.

Backblaze Event Notifications can help.This new B2 Cloud Storage feature can help you streamline a range of your production tasks—like automatically starting transcoding of video and distributing new images—across your preferred workflow tools. 

Today, I’m sharing five ways you can use Backblaze Event Notifications to operationalize media production efficiencies. If you’re interested in Event Notifications for applications, check out this post; and stay tuned for a future post on how to use Event Notifications for IT backup.

Event Notifications for media production: Simplified automation

Event Notifications monitors your B2 Cloud Storage for data changes that you designate—think raw video uploads, content version updates, deletions, etc.—and delivers near real-time alerts where you want them about these changes. These alerts can be used to create awareness faster, and even more powerfully, to initiate streamlined end-to-end processes that can save you time and hassle, and avoid unnecessary manual tasks and/or the cost of complex intermediaries.

What are webhooks?

Webhooks, if you’re not familiar with the term, are HTTP-based callback functions that enable event-based communications between software applications. Backblaze Event Notifications can uniquely work with any external service that accepts webhooks. This means you can use it to your advantage across your media production workflow—and this is novel when most vendors’ alerts features are limited to closed ecosystems or require significant and sometimes costly workarounds to communicate beyond a limited set of production tools.

Top 5 use cases for media production

Here are specific, practical ways people producing and managing media can take advantage of Event Notifications for immediate benefits.

1. New content processing

Event Notifications can be used to trigger tasks immediately after new content is uploaded. Imagine one of your team members uploads a video or image: Event Notifications can be sent to a transcoding service to format it and a tagging service to categorize it for better content organization. Set up to furthermore extract valuable metadata too—all in near real time, without manual intervention. 

General workflow (abbreviated)

By automating these processes, companies can ensure that user-generated content is formatted correctly, appropriately tagged, and moderated without delay. This not only saves time but guarantees a consistent user experience.

What’s more, you can even go full Jedi Knight and handle errors programmatically with Event Notifications logic that triggers reprocessing tasks whenever issues arise.

2. Integrated alerts in go-to tools

Event Notifications can easily integrate with your communication tools like Slack and productivity tools like Zapier, to inform internal and external stakeholders of updates without them needing to check for them manually. Users have told us this is a great way to keep people updated when assets are added, updated, or advanced to key stages in production and post cycles—setting them up to consider taking downstream actions that don’t lend themselves to further process automation.

Asset change announcement workflow

Additionally, for teams using workflow tools such as Zapier to connect various services, Event Notifications makes it simple to trigger actions across multiple platforms, enabling powerful, automated workflows with your data in B2 Cloud Storage.

3. Over-the-top (OTT) streaming automation

Regardless of whether your streaming model is AVOD, TVOD, or SVOD, Event Notifications can help automate processing and distribution workflows. Users can enable them so that every time a new title is added to B2 Cloud Storage, it then triggers alerts that initiate transcoding, compression, and prep for delivery or playback via content delivery network (CDN).

OTT streaming platform workflow

4. Backup completion monitoring

An important (if unglamorous) aspect of managing media is backing it up for extra safekeeping. After all, it’s a precious asset worth a lot of money now and later. So whether you back up nightly, monthly, at project’s end, or on some other cadence, with Event Notifications, customers can set up to receive updates when their media backups are successfully uploaded to a Backblaze B2 Bucket—providing peace of mind when data is protected.

We’ve also had a few users already tell us that not seeing backup completion alerts when expected helped them realize that they had other, previously unknown workflow hiccups to address.

Backup complete workflow

Tangentially related, media organizations are also using Backblaze Cloud Replication to programmatically store their content to two or more geographically distributed locations for added protection—this isn’t the same as Event Notifications, but is another automation tool for enhancing your protection posture.

5. Monitor data usage

Since Event Notifications messages are sent within seconds of files being uploaded and deleted, and they contain the size of the file in question, you can easily and reliably track your data usage in near real time, helping you identify trends and potential issues. For example, if you know large raw files are coming in and then messages indicating much smaller than expected file sizes were uploaded, it can alert you to begin to QC it.

We’ve also seen such data monitoring prove highly beneficial to IT personnel who support them because the near real-time monitoring allows faster responses to situations as they are happening, thereby mitigating risks, reducing costs, and/or nipping issues in the bud so the production teams remain disruption and distraction free.

Monitoring workflow

Beyond these example use cases, Event Notifications opens up a wide range of possibilities for automating and optimizing workflows. This flexibility makes it easy to automate how your infrastructure interacts with and reacts to file changes in B2 Cloud Storage, simplifying workflows across your distributed services. So go ahead and get creative—and please do share with us the cool things you’re doing with Event Notifications.

Why Event Notifications matter for production workflows

The benefits of real-time notifications extend beyond simply saving time—they transform the way teams work, automate processes, and reduce the margin for error.

  • Awareness: Instant notifications for uploads, updates, or deletions keep everyone on the same page.
  • Actionable insights: Real-time alerts provide critical information that helps make informed decisions quickly.
  • Flexibility: Direct connections to services like media asset managers (MAMs), transcoding applications, and CDNs mean more choice to stick with your preferred stack and less lock-in to specific vendors or tools.
  • Cost efficiency: Automating tasks like media transcoding, data processing, or content delivery reduces the need for manual labor, saving on operational costs and freeing up resources for other strategic initiatives.

Improved security: By instantly alerting teams to changes or unusual activity, Event Notifications help maintain data integrity and support proactive security measures.

How Event Notifications compares

Unlike other offerings like Amazon’s messaging services, which are limited to specific ecosystems, Backblaze Event Notifications integrates directly with any service that accepts webhooks, offering true flexibility and avoiding vendor lock-in.

Event Notifications is also designed for at-least-once delivery, ensuring critical notifications are not missed. This reliability is important for teams building workflows that require precision and a level of consistency their end users expect. 

The pricing for Event Notifications is simple and transparent. Backblaze B2 Reserve customers enjoy unlimited free Event Notifications, while pay-as-you-go Backblaze B2 customers enjoy 2,500 calls per day free and then $0.004 per 10,000 transactions. This straightforward pricing applies no matter the service receiving the notification. This enables businesses to confidently scale their event-driven workflows, knowing exactly what to expect in terms of costs, regardless of the services they choose to integrate with. 

Ready to add automation to your media tasks?

For existing customers working with a Backblaze account manager, Event Notifications is already enabled for you, and your account manager can assist with any questions. If you’re an existing customer not currently working with an account manager, please contact our Support team to request access to Event Notifications. 

New customers can contact our Sales team to learn more about how Event Notifications can streamline workflows and how to get started.

Once Event Notifications are enabled, log in to your Backblaze B2 account, navigate to the Buckets page, and click on the Event Notifications section. From there, you can set up notification rules for the events you want to track or configure notifications using our API.

For detailed instructions and best practices, visit our Event Notifications documentation.

The post 5 Ways to Use Event Notifications to Advance Your Media Better, Faster appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Hybrid Cloud Journey using Amazon Outposts and AWS Local Zones

Post Syndicated from Arun Chellappa Ganesan original https://aws.amazon.com/blogs/architecture/hybrid-cloud-journey-using-amazon-outposts-and-aws-local-zones/

This post was co-written with Amy Flanagan, Vice President of Architecture and leader of the Virtual Architecture Team (VAT) at athenahealth, and Anusha Dharmalingam, Executive Director and Senior Architect at athenahealth.

athenahealth has embarked on an ambitious journey to modernize its technology stack by leveraging AWS’s hybrid cloud solutions. This transformation aims to enhance scalability, performance, and developer productivity, ultimately improving the quality of care provided to its patients.

athenahealth’s core products, including revenue cycle management, electronic health records, and patient engagement portals, have been built and refined over 25 years. The company initially deployed its Perl-based web application stack centrally in data centers, allowing it to scale horizontally to meet the growing demands of healthcare providers. However, as the company expanded, it encountered significant scaling and operational challenges in maintaining legal applications due to its monolithic architecture and tightly coupled codebase.

The need for modernization

With a legacy system acting as a multi-purpose database, athenahealth faced issues with developer productivity and operational efficiency. The monolithic architecture led to complex dependencies and made it difficult to implement new features. Realizing the need to modernize, athenahealth decided to refactor its applications and move to the cloud, taking advantage of AWS’s robust infrastructure and services.

Decomposing monoliths to microservices

athenahealth adopted the strangler fig pattern to decompose its monolithic applications into microservices. Starting with peripheral services, they gradually moved to core services, using containers and modern development practices. 80% of athenahealth’s AWS footprint are containerized workloads deployed on Amazon Elastic Container Service (Amazon ECS). Java became the primary language for these microservices, with purpose-built databases like Amazon DynamoDB, Amazon RDS for PostgreSQL, and Amazon OpenSearch.

Event-driven communication between services was facilitated through Amazon EventBridge, Amazon Managed Streaming for Apache Kafka (Amazon MSK), and Amazon Simple Queue Service (Amazon SQS). A data lake was established on Amazon Simple Storage Service (Amazon S3), fed by change data capture from relational databases. Despite progress, refactoring core services proved time-consuming and challenging.

Introducing AWS Outposts and AWS Local Zones

To address these challenges, athenahealth leveraged AWS Local Zones and AWS Outposts, extending AWS infrastructure and services to their on-premises data centers. This hybrid cloud approach allowed athenahealth to deploy modernized code while maintaining low-latency access to existing databases. Deployment across both AWS Local Zones close to the datacenter and AWS Outposts in the datacenter enabled athenahealth to get a highly available hybrid architecture. Local Zones offers additional elasticity, making it suitable for specific use cases. Additionally, the combination of deployment solutions enables optimal access to athenahealth on-premises services and AWS Regional services.

Benefits of AWS Outposts and AWS Local Zones

  • Scalability and performance: Outposts and Local Zones enabled athenahealth to curb the growth of their monolithic codebase, allowing for seamless integration of modern microservices with existing systems.
  • Developer productivity: Developers were able to focus on container-based workloads, using familiar tools and environments, thereby reducing context switching and improving efficiency.
  • Operational efficiency: By running containerized applications on Outposts and Local Zones, athenahealth achieved consistent performance and reliability, crucial for healthcare applications.

Hybrid cloud architecture

athenahealth’s hybrid cloud architecture includes two data centers geographically distributed for high availability and disaster recovery. As shown in Figure 1, the company operates two data centers that are geographically distributed, each housing two Outposts and connecting to two Local Zones. This configuration not only supports geo-proximity-based traffic distribution for optimal performance but also establishes a primary and standby setup for disaster recovery purposes. By connecting these Outposts to separate AWS Regions, athenahealth achieves additional redundancy, enhancing their system’s resilience and ensuring continuous operation. In addition, within a single Region the deployment across Outpost and Local Zone provides high availability for the applications. This hybrid setup enables athenahealth to seamlessly integrate their legacy monolithic application with modernized microservices. By using AWS Outposts and AWS Local Zones as an extension of their data centers, athenahealth can run containerized applications with low-latency access to on-premises databases. This architecture supports the company’s goals of curbing the growth of their monolithic codebase and improving developer productivity by allowing for consistent performance and reliability across their infrastructure. With two Outposts and two Local Zones deployed, athenahealth ensures that their critical healthcare services remain available and reliable, meeting the stringent demands of the industry.

AWS Outposts and AWS Local Zones at athenahealth

Figure 1. AWS Outposts and AWS Local Zones at athenahealth

Application deployment

athenahealth’s hybrid cloud architecture is designed to optimize the deployment of containerized workloads while ensuring efficient use of AWS Outposts’ capacity and elastic AWS Local Zone capacity. By leveraging Amazon Elastic Kubernetes Service (EKS), athenahealth deploys application containers on Outposts and AWS Local Zones, enabling low-latency access to on-premises databases. The control plane for these applications is managed in the AWS Region, while the worker nodes run locally on the Outposts and Local Zones. This setup ensures that critical applications requiring immediate data access can operate with minimal latency, thereby maintaining high performance and reliability.

To further optimize the use of AWS resources, athenahealth deploys non-latency-sensitive services, such as logging, monitoring, and CI/CD, directly in AWS Regions, as shown in Figure 2. These services do not require direct access to on-premises databases, allowing athenahealth to preserve the limited capacity of Outposts for applications that truly benefit from low-latency access. By strategically dividing the deployment of applications between Outposts and Local Zones and AWS Regions, athenahealth achieves a balanced, efficient, and scalable hybrid cloud environment that supports the company’s ongoing modernization efforts.

Amazon EKS on Amazon Outposts

Figure 2. Amazon EKS on Amazon Outposts

Primary use cases

athenahealth’s primary use cases for their hybrid cloud architecture focus on curbing the growth of their monolithic codebase while facilitating modernization and cloud migration. By leveraging AWS Outposts and AWS Local Zones, they supported two key use cases:

  • Enabling microservices running in AWS Regions to access on-premises databases with low latency
  • Offloading certain features of their monolithic application to Outposts and Local Zones, as shown in Figure 3

This approach reduces the load on legacy systems and enhances service delivery. These strategies allow athenahealth to maintain efficient operations and accelerate their transition to a hybrid cloud-based infrastructure.

Microservices running in AWS Regions interact with on-premises databases through Outposts and Local Zones, ensuring low-latency data access

Figure 3. Microservices running in AWS Regions interact with on-premises databases through Outposts and Local Zones, ensuring low-latency data access

Conclusion

This technology transformation is a significant step forward, enabling athenahealth to be more agile, efficient, and responsive to the evolving needs of its vast network of healthcare providers and patients. athenahealth’s journey to AWS hybrid cloud showcases the transformative power of modernizing legacy systems. With increased scalability, improved application performance, and streamlined developer workflows, the company can now focus even more on its core mission of delivering innovative, patient-centric solutions that improve health outcomes. As athenahealth progresses, it will continue to refine its hybrid cloud strategy, ensuring the delivery of high-quality healthcare services to clinicians and patients alike.

Further reading

Automate Your Data Workflows with Backblaze B2 Event Notifications

Post Syndicated from Bala Krishna Gangisetty original https://www.backblaze.com/blog/announcing-event-notifications/

A decorative image showing the Backblaze logo on a cloud with an alert notification.

Public Preview Update: July 31, 2024

Backblaze Event Notifications is now in public preview. If you’re interested in joining the waitlist, feel free to sign up here.

Backblaze believes companies should be able to store, use, and protect their data in whatever way is best for their business—and that doing so should be easy. That’s why we’re such fierce advocates for the open cloud and why today’s announcement is so exciting.

Event Notifications—available in public preview—gives businesses the freedom to build automated workloads across the different best-of-breed cloud platforms they use or want to use, saving time and money and improving end user experiences.

Here’s how: With Backblaze Event Notifications, any data changes within Backblaze B2 Cloud Storage—like uploads, updates, or deletions—can automatically trigger actions in a workflow, including transcoding video files, spooling up data analytics, delivering finished assets to end users, and many others. Importantly, unlike many other solutions currently available, Backblaze’s service doesn’t lock you into one platform or require you to use legacy tools from AWS.

So, to businesses that want to create an automated workflow that combines different compute, content delivery networks (CDN), data analytics, and whatever other cloud service: Now you can, with the bonus of cloud storage at a fifth of the rates of other solutions and free egress.

If you’re already a Backblaze customer, you can join the waiting list for the Event Notifications preview by signing up here. Once you’re admitted to the preview, the Event Notifications option will become visible in your Backblaze B2 account.

A screenshot of the where to find Event Notifications in your Backblaze account.

Not a Backblaze customer yet? Sign up for a free Backblaze B2 account and join the waitlist. Read on for more details on how Event Notifications can benefit you.

With Event Notifications, we can eliminate the final AWS component, Simple Queue Service (SQS), from our infrastructure. This completes our transition to a more streamlined and cost-effective tech stack. It’s not just about simplifying operations—it’s about achieving full independence from legacy systems and future-proofing our infrastructure.


— Oleh Aleynik, Senior Software Engineer and Co-Founder at CloudSpot.

A Deeper Dive on Backblaze’s Event Notifications Service

Event Notifications is a service designed to streamline and automate data workflows for Backblaze B2 customers. Whether it’s compressing objects, transcoding videos, or transforming data files, Event Notifications empowers you to orchestrate complex, multistep processes seamlessly.

The top line benefit of Event Notifications is its ability to trigger processing workflows automatically whenever data changes on Backblaze B2. This means that as soon as new data is uploaded, changed, or deleted, the relevant processing steps can be initiated without manual intervention. This automation not only saves time and resources, but it also ensures that workflows are consistently executed with precision, free from human errors.

What sets Event Notifications apart is its flexibility. Unlike some other solutions that are tied to specific target services, Event Notifications allows customers the freedom to choose the target services that best suit their needs. Whether it’s integrating with third-party applications, cloud services, or internal systems, Event Notifications seamlessly integrates into existing workflows, offering unparalleled versatility.

Finally, Event Notifications doesn’t only bring greater ease and efficiency to workflows, it is also designed for very easy enablement. Whether via browser UI or SDKs or APIs or CLI, it is incredibly simple to set up a notification rule and integrate it with your preferred target service. Simply choose your event type, set the criteria, and input your endpoint URL, and a new workflow can be configured in minutes.

Public Preview Update: July 31, 2024

Additional capabilities offered in the public preview include:

  • Retries: Event Notifications are automatically re-sent if the initial delivery attempt fails. This feature increases the reliability of Event Notifications by ensuring that temporary issues do not result in missed events, thus maintaining the integrity of your event-driven workflows.
  • Delivery: Event Notifications are designed for the at-least-once delivery guarantee to ensure Event Notifications are delivered reliably, even in the presence of network or system failures.

What Is Backblaze B2 Event Notifications Good For?

By leveraging Event Notifications, Backblaze B2 customers can simplify their data processing pipelines, reduce manual effort, and increase operational efficiency. With the ability to automate repetitive tasks and handle millions of objects per day, businesses can focus on extracting insights from their data rather than managing the logistics of data processing.

A diagram showing the steps of event notifications.

Automating tasks: Event Notifications allows users to trigger automated actions in response to changes in stored objects like upload, delete, and hide actions, streamlining complex data processing tasks.

Orchestrating workflows: Users can orchestrate multi-step workflows, such as compressing files, transcoding videos, or transforming data formats, based on specific object events.

Integrating with services: The feature offers flexible integration capabilities, enabling seamless interaction with various services and tools to enhance data processing and management.

Monitoring changes: Users can efficiently monitor and track changes to stored objects, ensuring timely responses to evolving data requirements and faster security response to safeguard critical assets.

What Are Some of the Key Capabilities of Backblaze B2 Event Notifications?

  • Flexible Implementation: Event Notifications are sent as HTTP POST requests to the desired service or endpoint within your infrastructure or any other cloud service. This flexibility ensures seamless integration with your existing workflows. For instance, your endpoint could be Fastly Compute, AWS Lambda, Azure Functions, or Google Cloud Functions, etc.
  • Event Categories: Specify the types of events you want to be notified about, such as when files are uploaded and deleted. This allows you to receive notifications tailored to your specific needs. For instance, you have the flexibility to specify different methods of object creation, such as copying, uploading, or multipart replication, to trigger event notifications. You can also manage Event Notification rules through UI or API.
  • Filter by Prefix: Define prefixes to filter events, enabling you to narrow down notifications to specific sets of objects or directories within your storage on Backblaze B2. For instance, if your bucket contains audio, video, and text files organized into separate prefixes, you can specify the prefix for audio files to receive event notifications exclusively for audio files.
  • Custom Headers: Include personalized HTTP headers in your event notifications to provide additional authentication or contextual information when communicating with your target endpoint. For example, you can use these headers to add necessary authentication tokens or API keys for your target endpoint, or include any extra metadata related to the payload to offer contextual information to your webhook endpoint, and more.
  • Signed Notification Messages: You can configure outgoing messages to be signed by the Event Notifications service, allowing you to validate signatures and verify that each message was generated by Backblaze B2 and not tampered with in transit.
  • Test Rule Functionality: Validate the functionality of your target endpoint by testing event notifications before deploying them into action. This allows you to ensure that your integration with your target endpoint is set up correctly and functioning as expected.

Want to Learn More About Event Notifications?

Event Notifications represents a significant advancement in data management and automation for Backblaze B2 users. By providing a flexible and powerful capability for orchestrating data processing workflows, Backblaze continues to empower businesses to unlock the full potential of their data with ease and efficiency.

Join the Waitlist ➔ 

The post Automate Your Data Workflows with Backblaze B2 Event Notifications appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

What Is Hybrid Cloud?

Post Syndicated from Molly Clancy original https://www.backblaze.com/blog/confused-about-the-hybrid-cloud-youre-not-alone/

An illustration of clouds computers and servers.
Editor’s note: This post has been updated since it was originally published in 2017.

The term hybrid cloud has been around for a while—we originally published this explainer in 2017. But time hasn’t necessarily made things clearer. Maybe you hear folks talk about your company’s hybrid cloud approach, but what does that really mean? If you’re confused about the hybrid cloud, you’re not alone. 

Hybrid cloud is a computing approach that uses both private and public cloud resources with some kind of orchestration between them. The term has been applied to a wide variety of IT solutions, so it’s no wonder the concept breeds confusion. 

In this post, we’ll explain what a hybrid cloud is, how it can benefit your business, and how to choose a cloud storage provider for your hybrid cloud strategy.

What Is the Hybrid Cloud?

A hybrid cloud is an infrastructure approach that uses both private and public resources. Let’s first break down those key terms:

  • Public cloud: When you use a public cloud, you are storing your data in another company’s internet-accessible data center. A public cloud service allows anybody to sign up for an account, and share data center resources with other customers or tenants. Instead of worrying about the costs and complexity of operating an on-premises data center, a cloud storage user only needs to pay for the cloud storage they need.
  • Private cloud: In contrast, a private cloud is specifically designed for a single tenant. Think of a private cloud as a permanently reserved private dining room at a restaurant—no other customer can use that space. As a result, private cloud services can be more expensive than public clouds. Traditionally, private clouds typically lived on on-premises infrastructure, meaning they were built and maintained on company property. Now, private clouds can be maintained and managed on-premises by an organization or by a third party in a data center. The key defining factor is that the cloud is dedicated to a single tenant or organization.

Those terms are important to know to understand the hybrid cloud architecture approach. Hybrid clouds are defined by a combined management approach, which means there is some type of orchestration between the private and public environments that allows workloads and data to move between them in a flexible way as demands, needs, and costs change. This gives you flexibility when it comes to data deployment and usage.  

In other words, if you have some IT resources on-premises that you are replicating or sharing with an external vendor—congratulations, you have a hybrid cloud!

Hybrid cloud refers to a computing architecture that is made up of both private cloud resources and public cloud resources with some kind of orchestration between them.

Hybrid Cloud Examples

Here are a few examples of how a hybrid cloud can be used:

  1. As an active archive: You might establish a protocol that says all accounting files that have not been changed in the last year, for example, are automatically moved off-premises to cloud storage archive to save cost and reduce the amount of storage needed on-site. You can still access the files; they are just no longer stored on your local systems. 
  2. To meet compliance requirements: Let’s say some of your data is subject to strict data privacy requirements, but other data you manage isn’t as closely protected. You could keep highly regulated data on premises in a private cloud and the rest of your data in a public cloud. 
  3. To scale capacity: If you’re in an industry that experiences seasonal or frequent spikes like retail or ecommerce, these spikes can be handled by a public cloud which provides the elasticity to deal with times when your data needs exceed your on-premises capacity.
  4. For digital transformation: A hybrid cloud lets you adopt cloud resources in a phased approach as you expand your cloud presence.

Hybrid Cloud vs. Multi-cloud: What’s the Diff?

You wouldn’t be the first person to think that the terms multi-cloud and hybrid cloud appear similar. Both of these approaches involve using multiple clouds. However, multi-cloud uses two clouds of the same type in combination (i.e., two or more public clouds) and hybrid cloud approaches combine a private cloud with a public cloud. One cloud approach is not necessarily better than the other—they simply serve different use cases. 

For example, let’s say you’ve already invested in significant on-premises IT infrastructure, but you want to take advantage of the scalability of the cloud. A hybrid cloud solution may be a good fit for you. 

Alternatively, a multi-cloud approach may work best for you if you are already in the cloud and want to mitigate the risk of a single cloud provider having outages or issues. 

Hybrid Cloud Benefits

A hybrid cloud approach allows you to take advantage of the best elements of both private and public clouds. The primary benefits are flexibility, scalability, and cost savings.

Benefit 1: Flexibility and Scalability

One of the top benefits of the hybrid cloud is its flexibility. Managing IT infrastructure on-premises can be time consuming and expensive, and adding capacity requires advance planning, procurement, and upfront investment

The public cloud is readily accessible and able to provide IT resources whenever needed on short notice. For example, the term “cloud bursting” refers to the on-demand and temporary use of the public cloud when demand exceeds resources available in the private cloud. A private cloud, on the other hand, provides the absolute fastest access speeds since it is generally located on-premises. (But cloud providers are catching up fast, for what it’s worth.) For data that is needed with the absolute lowest levels of latency, it may make sense for the organization to use a private cloud for current projects and store an active archive in a less expensive, public cloud.

Benefit 2: Cost Savings

Within the hybrid cloud framework, the public cloud segment offers cost-effective IT resources, eliminating the need for upfront capital expenses and associated labor costs. IT professionals gain the flexibility to optimize configurations, choose the most suitable service provider, and determine the optimal location for each workload. This strategic approach reduces costs by aligning resources with specific tasks. Furthermore, the ability to easily scale, redeploy, or downsize services enhances efficiency, curbing unnecessary expenses and contributing to overall cost savings.

Comparing Private vs. Hybrid Cloud Storage Costs

To understand the difference in storage costs between a purely on-premises solution and a hybrid cloud solution, we’ll present two scenarios. For each scenario, we’ll use data storage amounts of 100TB, 1PB, and 2PB. Each table is the same format, all we’ve done is change how the data is distributed: private (on-premises) or public (off-premises). We are using the costs for our own Backblaze B2 Cloud Storage in this example. The math can be adapted for any set of numbers you wish to use.

Scenario 1    100% of data on-premises storage

    Data Stored
  Data Stored On-premises: 100%   100TB 1,000TB 2,000TB
On-premises cost range   Monthly Cost
  Low — $12/TB/Month   $1,200 $12,000 $24,000
  High — $20/TB/Month   $2,000 $20,000 $40,000

Scenario 2    20% of data on-premises with 80% public cloud storage (Backblaze B2)

    Data Stored
  Data Stored On-premises: 20%   20TB 200TB 400TB
  Data Stored in the Cloud: 80%   80TB 800TB 1,600TB
On-premises cost range   Monthly Cost
  Low — $12/TB/Month   $240 $2,400 $4,800
  High — $20/TB/Month   $400 $4,000 $8,000
Public cloud cost range   Monthly Cost
  Low — $6/TB/Month (Backblaze B2)   $480 $4,800 $9,600
  High — $20/TB/Month   $1,600 $16,000 $32,000
On-premises + public cloud cost range   Monthly Cost
  Low   $720 $7,200 $14,400
  High   $2,000 $20,000 $40,000

As you can see, using a hybrid cloud solution and storing 80% of the data in the cloud with a provider like Backblaze B2 can result in significant savings over storing only on-premises.

Choosing a Cloud Storage Provider for Your Hybrid Cloud

Okay, so you understand the benefits of using a hybrid cloud approach, what next? Determining the right mix of cloud services may be intimidating because there are so many public cloud options available. Fortunately, there are a few decision factors you can use to simplify setting up your hybrid cloud solution. Here’s what to think about when choosing a public cloud storage provider:

  • Ease of use: Avoiding a steep learning curve can save you hours of work effort in managing your cloud deployments. By contrast, overly complicated pricing tiers or bells and whistles you don’t need can slow you down.
  • Data security controls: Compare how each cloud provider facilitates proper data controls. For example, take a look at features like authentication, Object Lock, and encryption.
  • Data egress fees: Some cloud providers charge additional fees for data egress (i.e., removing data from the cloud). These fees can make it more expensive to switch between providers. In addition to fees, check the data speeds offered by the provider.
  • Interoperability: Flexibility and interoperability are key reasons to use cloud services. Before signing up for a service, understand the provider’s integration ecosystem. A lack of needed integrations may place a greater burden on your team to keep the service running effectively.
  • Storage tiers: Some providers offer different storage tiers where you sacrifice access for lower costs. While the promise of inexpensive cold storage can be attractive, evaluate whether you can afford to wait hours or days to retrieve your data.
  • Pricing transparency: Pay careful attention to the cloud provider’s pricing model and tier options. Consider building a spreadsheet to compare a shortlist of cloud providers’ pricing models.

When Hybrid Cloud Might Not Always Be the Right Fit

The hybrid cloud may not always be the optimal solution, particularly for smaller organizations with limited IT budgets that might find a purely public cloud approach more cost-effective. The substantial setup and operational costs of private servers could be prohibitive.

A thorough understanding of workloads is crucial to effectively tailor the hybrid cloud, ensuring the right blend of private, public, and traditional IT resources for each application and maximizing the benefits of the hybrid cloud architecture.

So, Should You Go Hybrid?

Big picture, anything that helps you respond to IT demands quickly, easily, and affordably is a win. With a hybrid cloud, you can avoid some big up-front capital expenses for in-house IT infrastructure, making your CFO happy. Being able to quickly spin up IT resources as they’re needed will appeal to the CTO and VP of operations.

So, given all that, we’ve arrived at the bottom line and the question is, should you or your organization embrace hybrid cloud infrastructure?According to Flexera’s 2023 State of the Cloud report, 72% of enterprises utilize a hybrid cloud strategy. That indicates that the benefits of the hybrid cloud appeal to a broad range of companies.

If an organization approaches implementing a hybrid cloud solution with thoughtful planning and a structured approach, a hybrid cloud can deliver on-demand flexibility, empower legacy systems, and applications with new capabilities, and become a catalyst for digital transformation. The result can be an elastic and responsive infrastructure that has the ability to quickly adapt to changing demands of the business.

As data management professionals increasingly recognize the advantages of the hybrid cloud, we can expect more and more of them to embrace it as an essential part of their IT strategy.

Tell Us What You’re Doing With the Hybrid Cloud

Are you currently embracing the hybrid cloud, or are you still uncertain or hanging back because you’re satisfied with how things are currently? We’d love to hear your comments below on how you’re approaching your cloud architecture decisions.

FAQs About Hybrid Cloud

What exactly is a hybrid cloud?

Hybrid cloud is a computing approach that uses both private and public cloud resources with some kind of orchestration between them.

What is the difference between hybrid and multi-cloud?

Multi-cloud uses two clouds of the same type in combination (i.e., two or more public clouds) and hybrid cloud approaches combine a private cloud with a public cloud. One cloud approach is not necessarily better than the other—they simply serve different use cases.

What is a hybrid cloud architecture?

Hybrid cloud architecture is any kind of IT architecture that combines both the public and private clouds. Many organizations use this term to describe specific software products that provide solutions which combine the two types of clouds.

What are hybrid clouds used for?

Organizations will often use hybrid clouds to create redundancy and scalability for their computing workload. A hybrid cloud is a great way for a company to have extra fallback options to continue offering services even when they have higher than usual levels of traffic, and it can also help companies scale up their services over time as they need to offer more options.

The post What Is Hybrid Cloud? appeared first on Backblaze Blog | Cloud Storage & Cloud Backup.

The Power of Specialized Cloud Providers: A Game Changer for SaaS Companies

Post Syndicated from Amrit Singh original https://www.backblaze.com/blog/the-power-of-specialized-cloud-providers-a-game-changer-for-saas-companies/

A decorative image showing a cloud with the Backblaze logo, then logos hanging off it it for Vultr, Fastly, Equinix metal, Terraform, and rclone.

“Nobody ever got fired for buying AWS.” It’s true: AWS’s one-size-fits-all solution worked great for most businesses, and those businesses made the shift away from the traditional model of on-prem and self-hosted servers—what we think of as Cloud 1.0—to an era where AWS was the cloud, the one and only, which is what we call Cloud 2.0. However, as the cloud landscape evolves, it’s time to question the old ways. Maybe nobody ever got fired for buying AWS, but these days, you can certainly get a lot of value (and kudos) for exploring other options. 

Developers and IT teams might hesitate when it comes to moving away from AWS, but AWS comes with risks, too. If you don’t have the resources to manage and maintain your infrastructure, costs can get out of control, for one. As we enter Cloud 3.0 where the landscape is defined by the open, multi-cloud internet, there is an emerging trend that is worth considering: the rise of specialized cloud providers.

Today, I’m sharing how software as a service (SaaS) startups and modern businesses can take advantage of these highly-focused, tailored services, each specializing and excelling in specific areas like cloud storage, content delivery, cloud compute, and more. Building on a specialized stack offers more control, return on investment, and flexibility, while being able to achieve the same performance you expect from hyperscaler infrastructure.

From a cost of goods sold perspective, AWS pricing wasn’t a great fit. From an engineering perspective, we didn’t want a net-new platform. So the fact that we got both with Backblaze—a drop-in API replacement with a much better cost structure—it was just a no-brainer.

—Rory Petty, Co-Founder & CTO, Tribute

The Rise of Specialized Cloud Providers

Specialized providers—including content delivery networks (CDNs) like Fastly, bunny.net, and Cloudflare, as well as cloud compute providers like Vultr—offer services that focus on a particular area of the infrastructure stack. Rather than trying to be everything to everyone, like the hyperscalers of Cloud 2.0, they do one thing and do it really well. Customers get best-of-breed services that allow them to build a tech stack tailored to their needs. 

Use Cases for Specialized Cloud Providers

There are a number of businesses that might benefit from switching from hyperscalers to specialized cloud providers, including:

In order for businesses to take advantage of the benefits (since most applications rely on more than just one service), these services must work together seamlessly. 

Let’s Take a Closer Look at How Specialized Stacks Can Work For You

If you’re wondering how exactly specialized clouds can “play well with each other,” we ran a whole series of application storage webinars that talk through specific examples and uses cases. I’ll share what’s in it for you below.

1. Low Latency Multi-Region Content Delivery with Fastly and Backblaze

Did you know a 100-millisecond delay in website load time can hurt conversion rates by 7%? In this session, Pat Patterson from Backblaze and Jim Bartos from Fastly discuss the importance of speed and latency in user experience. They highlight how Backblaze’s B2 Cloud Storage and Fastly’s content delivery network work together to deliver content quickly and efficiently across multiple regions. Businesses can ensure that their content is delivered with low latency, reducing delays and optimizing user experience regardless of the user’s location.

2. Scaling Media Delivery Workflows with bunny.net and Backblaze

Delivering content to your end users at scale can be challenging and costly. Users expect exceptional web and mobile experiences with snappy load times and zero buffering. Anything less than an instantaneous response may cause them to bounce. 

In this webinar, Pat Patterson demonstrates how to efficiently scale your content delivery workflows from content ingestion, transcoding, storage, to last-mile acceleration via bunny.net CDN. Pat demonstrates how to build a video hosting platform called “Cat Tube” and shows how to upload a video and play it using HTML5 video element with controls. Watch below and download the demo code to try it yourself.

3. Balancing Cloud Cost and Performance with Fastly and Backblaze

With a global economic slowdown, IT and development teams are looking for ways to slash cloud budgets without compromising performance. E-commerce, SaaS platforms, and streaming applications all rely on high-performant infrastructure, but balancing bandwidth and storage costs can be challenging. In this 45-minute session, we explored how to recession-proof your growing business with key cloud optimization strategies, including ways to leverage Fastly’s CDN to balance bandwidth costs while avoiding performance tradeoffs.

4. Reducing Cloud OpEx Without Sacrificing Performance and Speed

Greg Hamer from Backblaze and DJ Johnson from Vultr explore the benefits of building on best-of-breed, specialized cloud stacks tailored to your business model, rather than being locked into traditional hyperscaler infrastructure. They cover real-world use cases, including:

  • How Can Stock Photo broke free from AWS and reduced their cloud bill by 55% while achieving 4x faster generation.
  • How Monument Labs launched a new cloud-based photo management service to 25,000+ users.
  • How Black.ai processes 1000s of files simultaneously, with a significant reduction of infrastructure costs.

5. Leveling Up a Global Gaming Platform while Slashing Cloud Spend by 85%

James Ross of Nodecraft, an online gaming platform that aims to make gaming online easy, shares how he moved his global game server platform from Amazon S3 to Backblaze B2 for greater flexibility and 85% savings on storage and egress. He discusses the challenges of managing large files over the public internet, which can result in expensive bandwidth costs. By storing game titles on Backblaze B2 and delivering them through Cloudflare’s CDN, they achieve reduced latency since games are cached at the edge, and pay zero egress fees thanks to the Bandwidth Alliance. Nodecraft also benefited from Universal Data Migration, which allows customers to move large amounts of data from any cloud services or on-premises storage to Backblaze’s B2 Cloud Storage, managed by Backblaze and free of charge.

Migrating From a Hyperscaler

Though it may seem daunting to transition from a hyperscaler to a specialized cloud provider, it doesn’t have to be. Many specialized providers offer tools and services to make the transition as smooth as possible. 

  • S3-compatible APIs, SDKs, CLI: Interface with storage as you would with Amazon S3—switching can be as easy as dropping in a new storage target.
  • Universal Data Migration: Free and fully managed migrations to make switching as seamless as possible.
  • Free egress: Move data freely with the Bandwidth Alliance and other partnerships between specialized cloud storage providers.

As the decision maker at your growing SaaS company, it’s worth considering whether a specialized cloud stack could be a better fit for your business. By doing so you could potentially unlock cost savings, improve performance, and gain flexibility to adapt your services to your unique needs. The one-size-fits-all is no longer the only option out there. 

Want to Test It Out Yourself?

Take a proactive approach to cloud cost management: Get 10GB free to test and validate your proof of concept (POC) with Backblaze B2. All it takes is an email to get started.

Download the Ransomware Guide ➔ 

The post The Power of Specialized Cloud Providers: A Game Changer for SaaS Companies appeared first on Backblaze Blog | Cloud Storage & Cloud Backup.

The Free Credit Trap: Building SaaS Infrastructure for Long-Term Sustainability

Post Syndicated from Amrit Singh original https://www.backblaze.com/blog/the-free-credit-trap-building-saas-infrastructure-for-long-term-sustainability/

In today’s economic climate, cost cutting is on everyone’s mind, and businesses are doing everything they can to save money. But, it’s equally important that they can’t afford to compromise the integrity of their infrastructure or the quality of the customer experience. As a startup, taking advantage of free cloud credits from cloud providers like Amazon AWS, especially at a time like this, seems enticing. 

Using those credits can make sense, but it takes more planning than you might think to use them in a way that allows you to continue managing cloud costs once the credits run out. 

In this blog post, I’ll walk through common use cases for credit programs, the risks of using credits, and alternatives that help you balance growth and cloud costs.

The True Cost of “Free”

This post is part of a series exploring free cloud credits and the hidden complexities and limitations that come with these offers. Check out our previous installments:

The Shift to Cloud 3.0

As we see it, there have been three stages of “The Cloud” in its history:

Phase 1: What is the Cloud?

Starting around when Backblaze was founded in 2007, the public cloud was in its infancy. Most people weren’t clear on what cloud computing was or if it was going to take root. Businesses were asking themselves, “What is the cloud and how will it work with my business?”

Phase 2: Cloud = Amazon Web Services

Fast forward to 10 years later, and AWS and “The Cloud” started to become synonymous. Amazon had nearly 50% of market share of public cloud services, more than Microsoft, Google, and IBM combined. “The Cloud” was well-established, and for most folks, the cloud was AWS.

Phase 3: Multi-Cloud

Today, we’re in Phase 3 of the cloud. “The Cloud” of today is defined by the open, multi-cloud internet. Traditional cloud vendors are expensive, complicated, and seek to lock customers into their walled gardens. Customers have come to realize that (see below) and to value the benefits they can get from moving away from a model that demands exclusivity in cloud infrastructure.

An image displaying a Tweet from user Philo Hermans @Philo01 that says 

I migrated most infrastructure away from AWS. Now that I think about it, those AWS credits are a well-designed trap to create a vendor lock in, and once your credits expire and you notice the actual cost, chances are you are in shock and stuck at the same time (laughing emoji).
Source.

In Cloud Phase 3.0, companies are looking to reign in spending, and are increasingly seeking specialized cloud providers offering affordable, best-of-breed services without sacrificing speed and performance. How do you balance that with the draw of free credits? I’ll get into that next, and the two are far from mutually exclusive.

Getting Hooked on Credits: Common Use Cases

So, you have $100k in free cloud credits from AWS. What do you do with them? Well, in our experience, there are a wide range of use cases for credits, including:

  • App development and testing: Teams may leverage credits to run an app development proof of concept (PoC) utilizing Amazon EC2, RDS, and S3 for compute, database, and storage needs, for example, but without understanding how these will scale in the longer term, there may be risks involved. Spinning up EC2 instances can quickly lead to burning through your credits and getting hit with an unexpected bill.
  • Machine learning (ML): Machine learning models require huge amounts of computing power and storage. Free cloud credits might be a good way to start, but you can expect them to quickly run out if you’re using them for this use case. 
  • Data analytics: While free cloud credits may cover storage and computing resources, data transfer costs might still apply. Analyzing large volumes of data or frequently transferring data in and out of the cloud can lead to unexpected expenses.
  • Website hosting: Hosting your website with free cloud credits can eliminate the up front infrastructure spend and provide an entry point into the cloud, but remember that when the credits expire, traffic spikes you should be celebrating can crater your bottom line.
  • Backup and disaster recovery: Free cloud credits may have restrictions on data retention, limiting the duration for which backups can be stored. This can pose challenges for organizations requiring long-term data retention for compliance or disaster recovery purposes.

All of this is to say: Proper configuration, long-term management and upkeep, and cost optimization all play a role on how you scale on monolith platforms. It is important to note that the risks and benefits mentioned above are general considerations, and specific terms and conditions may vary depending on the cloud service provider and the details of their free credit offerings. It’s crucial to thoroughly review the terms and plan accordingly to maximize the benefits and mitigate the risks associated with free cloud credits for each specific use case. (And, given the complicated pricing structures we mentioned before, that might take some effort.)

Monument Uses Free Credits Wisely

Monument, a photo management service with a strong focus on security and privacy, utilized free startup credits from AWS. But, they knew free credits wouldn’t last forever. Monument’s co-founder, Ercan Erciyes, realized they’d ultimately lose money if they built the infrastructure for Monument Cloud on AWS.

He also didn’t want to accumulate tech debt and become locked in to AWS. Rather than using the credits to build a minimum viable product as fast as humanly possible, he used the credits to develop the AI model, but not to build their infrastructure. Read more about how they put AWS credits to use while building infrastructure that could scale as they grew.

➔ Read More

The Risks of AWS Credits: Lessons from Founders

If you’re handed $100,000 in credits, it’s crucial to be aware of the risks and implications that come along with it. While it may seem like an exciting opportunity to explore the capabilities of the cloud without immediate financial constraints, there are several factors to consider:

  1. The temptation to overspend: With a credit balance at your disposal just waiting to be spent, there is a possibility of underestimating the actual costs of your cloud usage. This can lead to a scenario where you inadvertently exhaust the credits sooner than anticipated, leaving you with unexpected expenses that may strain your budget.
  2. The shock of high bills once credits expire: Without proper planning and monitoring of your cloud usage, the transition from “free” to paying for services can result in high bills that catch you off guard. It is essential to closely track your cloud usage throughout the credit period and have a clear understanding of the costs associated with the services you’re utilizing. Or better yet, use those credits for a discrete project to test your PoC or develop your minimum viable product, and plan to build your long-term infrastructure elsewhere.
  3. The risk of vendor lock-in: As you build and deploy your infrastructure within a specific cloud provider’s ecosystem, the process of migrating to an alternative provider can seem complex and can definitely be costly (shameless plug: at Backblaze, we’ll cover your migration over 50TB). Vendor lock-in can limit your flexibility, making it challenging to adapt to changing business needs or take advantage of cost-saving opportunities in the future.

The problems are nothing new for founders, as the online conversation bears out.

First, there’s the old surprise bill:

A Tweet from user Ajul Sahul @anjuls that says 

Similar story, AWS provided us free credits so we though we will use it for some data processing tasks. The credit expired after one year and team forgot about the abandoned resources to give a surprise bill. Cloud governance is super importance right from the start.
Source.

Even with some optimization, AWS cloud spend can still be pretty “obscene” as this user vividly shows:

A Tweet from user DHH @dhh that says 

We spent $3,201,564.24 on cloud in 2022 at @37signals, mostly AWS. $907,837.83 on S3. $473,196.30 on RDS. $519,959.60 on OpenSearch. $123,852.30 on Elasticache. This is with long commits (S3 for 4 years!!), reserved instances, etc. Just obscene. Will publish full accounting soon.
Source.

There’s the founder raising rounds just to pay AWS bills:

A Tweet from user Guille Ojeda @itsguilleojeda that says 

Tech first startups raise their first rounds to pay AWS bills. By the way, there's free credits, in case you didn't know. Up to $100k. And you'll still need funding.
Source.

Some use the surprise bill as motivation to get paying customers.

Lastly, there’s the comic relief:

A tweet from user Mrinal Wahal @MrinalWahal that reads 

Yeah high credit card bills are scary but have you forgotten turning off your AWS instances?
Source.

Strategies for Balancing Growth and Cloud Costs

Where does that leave you today? Here are some best practices startups and early founders can implement to balance growth and cloud costs:

  1. Establishing a cloud cost management plan early on.
  2. Monitoring and optimizing cloud usage to avoid wasted resources.
  3. Leveraging multiple cloud providers.
  4. Moving to a new cloud provider altogether.
  5. Setting aside some of your credits for the migration.

1. Establishing a Cloud Cost Management Plan

Put some time into creating a well-thought-out cloud cost management strategy from the beginning. This includes closely monitoring your usage, optimizing resource allocation, and planning for the expiration of credits to ensure a smooth transition. By understanding the risks involved and proactively managing your cloud usage, you can maximize the benefits of the credits while minimizing potential financial setbacks and vendor lock-in concerns.

2. Monitoring and Optimizing Cloud Usage

Monitoring and optimizing cloud usage plays a vital role in avoiding wasted resources and controlling costs. By regularly analyzing usage patterns, organizations can identify opportunities to right-size resources, adopt automation to reduce idle time, and leverage cost-effective pricing options. Effective monitoring and optimization ensure that businesses are only paying for the resources they truly need, maximizing cost efficiency while maintaining the necessary levels of performance and scalability.

3. Leveraging Multiple Cloud Providers

By adopting a multi-cloud strategy, businesses can diversify their cloud infrastructure and services across different providers. This allows them to benefit from each provider’s unique offerings, such as specialized services, geographical coverage, or pricing models. Additionally, it provides a layer of protection against potential service disruptions or price increases from a single provider. Adopting a multi-cloud approach requires careful planning and management to ensure compatibility, data integration, and consistent security measures across multiple platforms. However, it offers the flexibility to choose the best-fit cloud services from different providers, reducing dependency on a single vendor and enabling businesses to optimize costs while harnessing the capabilities of various cloud platforms.

4. Moving to a New Cloud Provider Altogether

If you’re already deeply invested in a major cloud platform, shifting away can seem cumbersome, but there may be long-term benefits that outweigh the short term “pains” (this leads into the shift to Cloud 3.0). The process could involve re-architecting applications, migrating data, and retraining personnel on the new platform. However, factors such as pricing models, performance, scalability, or access to specialized services may win out in the end. It’s worth noting that many specialized providers have taken measures to “ease the pain” and make the transition away from AWS more seamless without overhauling code. For example, at Backblaze, we developed an S3 compatible API so switching providers is as simple as dropping in a new storage target.

5. Setting Aside Credits for the Migration

By setting aside credits for future migration, businesses can ensure they have the necessary resources to transition to a different provider without incurring significant up front expenses like egress fees to transfer large data sets. This strategic allocation of credits allows organizations to explore alternative cloud platforms, evaluate their pricing models, and assess the cost-effectiveness of migrating their infrastructure and services without worrying about being able to afford the migration.

Welcome to Cloud 3.0: Alternatives to AWS

In 2022, David Heinemeier Hansson, the creator of Basecamp and Hey, announced that he was moving Hey’s infrastructure from AWS to on-premises. Hansson cited the high cost of AWS as one of the reasons for the move. His estimate? “We stand to save $7m over five years from our cloud exit,” he said.  

Going back to on-premises solutions is certainly one answer to the problem of AWS bills. In fact, when we started designing Backblaze’s Personal Backup solution, we were faced with the same problem. Hosting data storage for our computer backup product on AWS was a non-starter—it was going to be too expensive, and our business wouldn’t be able to deliver a reasonable consumer price point and be solvent. So, we didn’t just invest in on-premises resources: We built our own Storage Pods, the first evolution of the Backblaze Storage Cloud. 

But, moving back to on-premises solutions isn’t the only answer—it’s just the only answer if it’s 2007 and your two options are AWS and on-premises solutions. The cloud environment as it exists today has better choices. We’ve now grown that collection of Storage Pods into the Backblaze B2 Storage Cloud, which delivers performant, interoperable storage at one-fifth the cost of AWS. And, we offer free egress to our content delivery network (CDN) and compute partners. Backblaze may provide an even more cost-effective solution for mid-sized SaaS startups looking to save on cloud costs while maintaining speed and performance.

As we transition to Cloud 3.0 in 2023 and beyond, companies are expected to undergo a shift, reevaluating their cloud spending to ensure long-term sustainability and directing saved funds into other critical areas of their businesses. The age of limited choices is over. The age of customizable cloud integration is here. 

So, shout out to David Heinemeier Hansson: We’d love to chat about your storage bills some time.

Want to Test It Yourself?

Take a proactive approach to cloud cost management: If you’ve got more than 50TB of data storage or want to check out our capacity-based pricing model, B2 Reserve, contact our Sales Team to test a PoC for free with Backblaze B2.

And, for the streamlined, self–serve option, all you need is an email to get started today.

FAQs About Cloud Spend

If you’re thinking about moving to Backblaze B2 after taking AWS credits, but you’re not sure if it’s right for you, we’ve put together some frequently asked questions that folks have shared with us before their migrations:

My cloud credits are running out. What should I do?

Backblaze’s Universal Data Migration service can help you off-load some of your data to Backblaze B2 for free. Speak with a migration expert today.

AWS has all of the services I need, and Backblaze only offers storage. What about the other services I need?

Shifting away from AWS doesn’t mean ditching the workflows you have already set up. You can migrate some of your data storage while keeping some on AWS or continuing to use other AWS services. Moreover, AWS may be overkill for small to midsize SaaS businesses with limited resources.

How should I approach a migration?

Identify the specific services and functionalities that your applications and systems require, such as CDN for content delivery or compute resources for processing tasks. Check out our partner ecosystem to identify other independent cloud providers that offer the services you need at a lower cost than AWS.

What CDN partners does Backblaze have?

With the ease of use, predictable pricing, zero egress, our joint solutions are perfect for businesses looking to reduce their IT costs, improve their operational efficiency, and increase their competitive advantage in the market. Our CDN partners include Fastly, bunny.net, and Cloudflare. And, we extend free egress to joint customers.

What compute partners does Backblaze have?

Our compute partners include Vultr and Equinix Metal. You can connect Backblaze B2 Cloud Storage with Vultr’s global compute network to access, store, and scale application data on-demand, at a fraction of the cost of the hyperscalers.

The post The Free Credit Trap: Building SaaS Infrastructure for Long-Term Sustainability appeared first on Backblaze Blog | Cloud Storage & Cloud Backup.

A Cyber Insurance Checklist: Learn How to Lower Risk to Better Secure Coverage

Post Syndicated from Kari Rivas original https://www.backblaze.com/blog/a-cyber-insurance-checklist-learn-how-to-lower-risk-to-better-secure-coverage/

A decorative image showing a cyberpig on a laptop with a shield blocking it from accessing a server.

If your business is looking into cyber insurance to protect your bottom line against security incidents, you’re in good company. The global market for cybersecurity insurance is projected to grow from 11.9 billion in 2022 to 29.2 billion by 2027.

But you don’t want to go into buying cyber security insurance blind. We put together this cyber insurance readiness checklist to help you strengthen your cyber resilience stance in order to better secure a policy and possibly a lower premium. (And even if you decide not to pursue cyber insurance, simply following some of these best practices will help you secure your company’s data.)

What is Cyber Insurance?

Cyber insurance is a specialty insurance product that is useful for any size business, but especially those dealing with large amounts of data. Before you buy cyber insurance, it helps to understand some fundamentals. Check out our post on cyber insurance basics to get up to speed.

Once you understand the basic choices available to you when securing a policy, or if you’re already familiar with how cyber insurance works, read on for the checklist.

Cyber Insurance Readiness Checklist

Cybersecurity insurance providers use their questionnaire and assessment period to understand how well-situated your business is to detect, limit, or prevent a cyber attack. They have requirements, and you want to meet those specific criteria to be covered at the most reasonable cost.

Your business is more likely to receive a lower premium if your security infrastructure is sound and you have disaster recovery processes and procedures in place. Though each provider has their own requirements, use the checklist below to familiarize yourself with the kinds of criteria a cyber insurance provider might look for. Any given provider may not ask about or require all these precautions; these are examples of common criteria. Note: Checking these off means your cyber resilience score is attractive to providers, though not a guarantee of coverage or a lower premium.

General Business Security

  • A business continuity/disaster recovery plan that includes a formal incident response plan is in place.
  • There is a designated role, group, or outside vendor responsible for information security.
  • Your company has a written information security policy.
  • Employees must complete social engineering/phishing training.
  • You set up antivirus software and firewalls.
  • You monitor the network in real-time.
  • Company mobile computing devices are encrypted.
  • You use spam and phishing filters for your email client.
  • You require two-factor authentication (2FA) for email, remote access to the network, and privileged user accounts.
  • You have an endpoint detection and response system in place.

Cloud Storage Security

  • Your cloud storage account is 2FA enabled. Note: Backblaze accounts have 2FA via SMS or via authentication apps using ToTP.
  • You encrypt data at rest and in transit. Note: Backblaze B2 provides server-side encryption (encryption at rest), and many of our partner integration tools, like Veeam, MSP360, and Archiware, offer encryption in transit.
  • You follow the 3-2-1 or 3-2-1-1-0 backup strategies and keep an air-gapped copy of your backup data (that is, a copy that’s not connected to your network).
  • You run backups frequently. You might consider implementing grandfather-father-son strategy for your cloud backups to meet this requirement.
  • You store backups off-site and in a geographically separate location. Note: Even if you keep a backup off-site, your cyber insurance provider may not consider this secure enough if your off-site copy is in the same geographic region or held at your own data center.
  • Your backups are protected from ransomware with object lock for data immutability.

AcenTek Adopts Cloud for Cyber Insurance Requirement

Learn how Backblaze customer AcenTek secured their data with B2 Cloud Storage to meet their cyber insurance provider’s requirement that backups be secured in a geographically distanced location.

By adding features like SSE, 2FA, and object lock to your backup security, insurance companies know you take data security seriously.

Cyber insurance provides the peace of mind that, when your company is faced with a digital incident, you will have access to resources with which to recover. And there is no question that by increasing your cybersecurity resilience, you’re more likely to find an insurer with the best coverage at the right price.

Ultimately, it’s up to you to ensure you have a robust backup strategy and security protocols in place. Even if you hope to never have to access your backups (because that might mean a security breach), it’s always smart to consider how fast you can restore your data should you need to, keeping in mind that hot storage is going to give you a faster recovery time objective (RTO) without any delays like those seen with cold storage like Amazon Glacier. And, with Backblaze B2 Cloud Storage offering hot cloud storage at cold storage prices, you can afford to store all your data for as long as you need—at one-fifth the price of AWS.

Get Started With Backblaze

Get started today with pay-as-you-go pricing, or contact our Sales Team to learn more about B2 Reserve, our all-inclusive, capacity-based bundles starting at 20TB.

The post A Cyber Insurance Checklist: Learn How to Lower Risk to Better Secure Coverage appeared first on Backblaze Blog | Cloud Storage & Cloud Backup.

New Whitepaper: Selecting & Designing Your Hybrid Connectivity Model

Post Syndicated from Santiago Freitas original https://aws.amazon.com/blogs/architecture/new-whitepaper-selecting-designing-your-hybrid-connectivity-model/

Introduction

Many organizations need to connect their on-premises data centers, remote sites, and the cloud. A hybrid network connects these different environments.

A modern organization uses an extensive array of IT resources. In the past, it was common to host these resources in an on-premises data center or a colocation facility. With the increased adoption of cloud computing, IT resources are delivered and consumed from cloud service providers over a network connection. In some cases, organizations have opted to migrate all existing IT resources to the cloud. In other cases, organizations maintain IT resources both on premises and in the cloud. In both cases, a common network is required to connect on-premises and cloud resources. Coexistence of on-premises and cloud resources is called “hybrid cloud” and the common network connecting them is referred to as a “hybrid network. “ Even if your organization keeps all of its IT resources in the cloud, it may still require hybrid connectivity to remote sites.

There are several connectivity models to choose from. Although having options adds flexibility, selecting the best option requires analysis of the business and technical requirements and the elimination of options that are not suitable. Requirements can be grouped together across considerations, such as: security, time to deploy, performance, reliability, communication model, scalability, and more. Once requirements are carefully collected, analyzed, and considered, network and cloud architects identify applicable AWS hybrid network building blocks and solutions. To identify and select the optimal model(s), architects must understand advantages and disadvantages of each model. There are also technical limitations that might cause an otherwise good model to be excluded.

Consideration covered in the whitepaper

Figure 1 – Consideration covered on the whitepaper.

A new whitepaper on Hybrid Connectivity describes AWS building blocks and the key things to consider when deciding which hybrid connectivity model is right for you. To help you determine the best solution for your business and technical requirements, we provide decision trees to guide you through the logical selection process as well as a customer use case to show how to apply the considerations and decision trees in practice.

Decision tree applied to Example Corp. Automotive use case

Figure 2: Example Corp. Automotive connection type decision tree

Contributors

Contributors to this new whitepaper on Hybrid Connectivity are: Marwan Al Shawi, AWS Solutions Architect; Santiago Freitas, AWS Head of Technology; Evgeny Vaganov, AWS Specialist Solutions Architect – Networking; and Tom Adamski, AWS Specialist Solutions Architect – Networking. Special thanks to Stephen Bird, AWS Senior Program Manager – Content.