Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=S0wyBWv_b2U
Instant Cameras Are Back… But Why?
Post Syndicated from Matt Granger original https://www.youtube.com/watch?v=bqqGFHMW39w
Краят на журналистиката
Post Syndicated from Дарина Сарелска original https://www.toest.bg/krayat-na-zhurnalistikata/

Журналистиката е на изчезване. Не ви го казвам аз. Казва го последното проучване на Института „Ройтерс“, което включва елита на новинарската индустрия в 51 държави по света.
Делът на песимистите за бъдещето на професията почти се е удвоил – от 10% през 2022 г. до 18% днес. Паралелно с това оптимизмът се срива – едва 38% от хората, които правят журналистика на най-високо ниво, казват, че професията ще има добро развитие в следващата година. Преди четири години този дял е бил около 60%.
Оптимизъм
Песимизъм
Причините?
Разбира се, виновникът за всичко тези дни – изкуственият интелект. Но не само. И не защото роботи пишат новините, а защото роботи променят пътя на читателите до тях.
Вместо да кликат към медийни сайтове, все повече потребители стигат до информацията директно в търсачката, която им дава синтетично обобщение, сглобено от чуждо (често безплатно) съдържание. Издателите очакват трафикът от търсачки към новинарските сайтове да спадне с около 40% през следващите три години именно заради тези т.нар. zero-click търсения.
Преди
Журналист
→
Медия
→
Търсачка / платформа
→
Читател
Сега
Журналист
→
Медия
→
AI / search
→
Синтетичен отговор
→
Читател
Ключовата промяна е, че читателят все по-често получава отговор, без да стига до оригиналния източник.
Има и друга причина – кризата на релевантност на традиционните медийни брандове, особено на комерсиалните. Години наред те се опитваха да запазят бизнес модела си, лутайки се между страх и неразбиране на социалните мрежи и опита да ги използват като прокси – вход към собствените си платформи, където да монетизират вниманието на аудиторията. Само че през това време публиката тихо се премести другаде, а порасна и нова, която никога не се е информирала от друг екран освен от телефона. За нея „телевизорът“ е YouTube, Instagram и TikTok.
Тук вече говорим за нещо по-дълбоко от технологична промяна. Това е поколенческа и екзистенциална криза.
Журналистиката не просто губи публика – тя губи връзката си с цели поколения и групи от обществото. Губи навика да им бъде нужна.
Политиците също успешно „помагат“ в делегитимирането на новинарските медии. Дали като ги приласкават и подкупват, дали като им викат fake news и мисирки, или просто като ги маргинализират чрез заобикаляне. Могат да си го позволят, защото социалните мрежи им дават достъп до същата, а понякога и до по-голяма публика без досадния посредник журналист, който прекъсва с въпроси. Не дай боже, критични. Или коригира твърдения. Често лъжливи.
„Няма места.“ Журналистиката след журналистите
Ако се чудите какво стана с медиите в България, този текст ви е напълно достатъчен, за да си дадете отговори на много въпроси. А иначе, вие въпроси може и да си задавате, но в много медии у нас вече няма кой да ги задава – гледайте какво нещо… Защо стана така – от Дарина Сарелска.
 Дарина Сарелска
Телевизионният фолклор пази спомена за Бойко Борисов и неговата реплика, че идването му в сутрешния блок на Нова телевизия при Ани Цолова и Виктор Николаев (2013–2017) му се струвало като ходене на зъболекар. Не ти е приятно, но трябва.
Сега вече не трябва.
Днес, макар да не е премиер, той има над 300 000 последователи във Facebook и понякога достига до 2 милиона гледания на клипче.
За сравнение: една рейтинг точка в България е около 70 000 души в общата демографска група – т.нар. 4+ (от 4 години нагоре), а сутрешните блокове в последните поне 15 години рядко правят повече от 4–5 рейтинг точки – дори и в най-добрите си времена. Сметката е проста: 300 000 гледания в най-добрия случай, ако станеш рано и отидеш до „телевизора“. А като се има предвид, че Facebook е предпочитаният източник за новини на българите, наравно с телевизиите, наистина не разбирам защо човек трябва да слага костюм и от кръста надолу и да бие път до близки и далечни студиа, за да му прекъсват мисълта.
Разбира се, телевизионните студиа бяха удобно обзаведени с хора, които не прекъсват мисли. Дали защото нямат с какво да ги прекъснат, дали заради смразяващия ефект на празните столчета.
Но това, струва ми се, е по-неуспешната стратегия за умъртвяване на журналистиката. Защото е твърде груба, твърде публична, а и успехът е често пирова победа. Все пак, каквото и да казват рейтингите, ясно е, че никой не гледа това, което в момента дават сутрин по bTV. Има и контрареакция, която дори и пренебрежимо малка, за да създаде реален бизнес проблем, e достатъчно голяма, за да създаде криза на влиянието. Не е удобно, когато в собствения ти ефир през ден ти повтарят, че си изпълнил политическа поръчка, включително собствените ти гости, дошли да се възползват от твоята публика, но и да ѝ отбележат, че седи на пресен гроб.
И да, това не е възпряло хората да си гледат „Ергенът“.
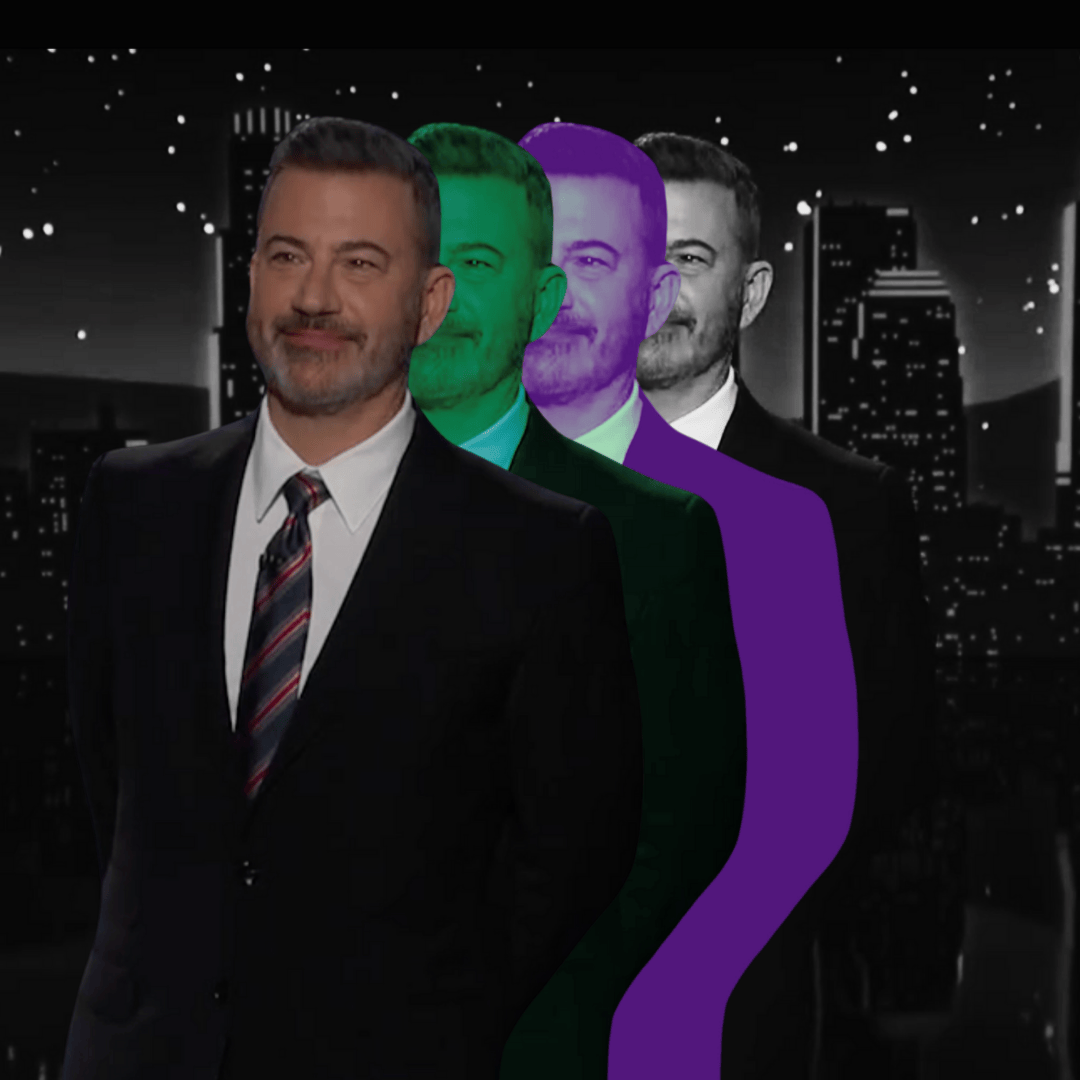
За сравнение, когато ABC се опитаха да спрат Джими Кимъл миналата есен и публиката възприе това като политически мотивирано решение под натиска на консервативни лидери и медии, реакцията беше 7 милиона отказали се от стрийминг услугите на компанията (Disney+ и Hulu). Седем милиона. Това е около един на всеки 30 потребители. И да, при платформи гиганти това не звучи като фатален удар. Но когато загубата се случи за няколко дни, дори и многомилиардни корпорации си взeмат бележка. Кимъл беше върнат на екран, а първият му епизод след прекъсването записа рекордна гледаемост.
Свободата на словото като палачинка
„Искам да благодаря на хората, които не подкрепят нито шоуто ми, нито какво мисля, но въпреки това подкрепят правото ми да споделям вярванията си“, каза Джими Кимъл в първия си монолог след връщането на шоуто му на екран. Защо свободата на словото има значение за всичко и всички – от Светла Енчева.
 Светла Енчева
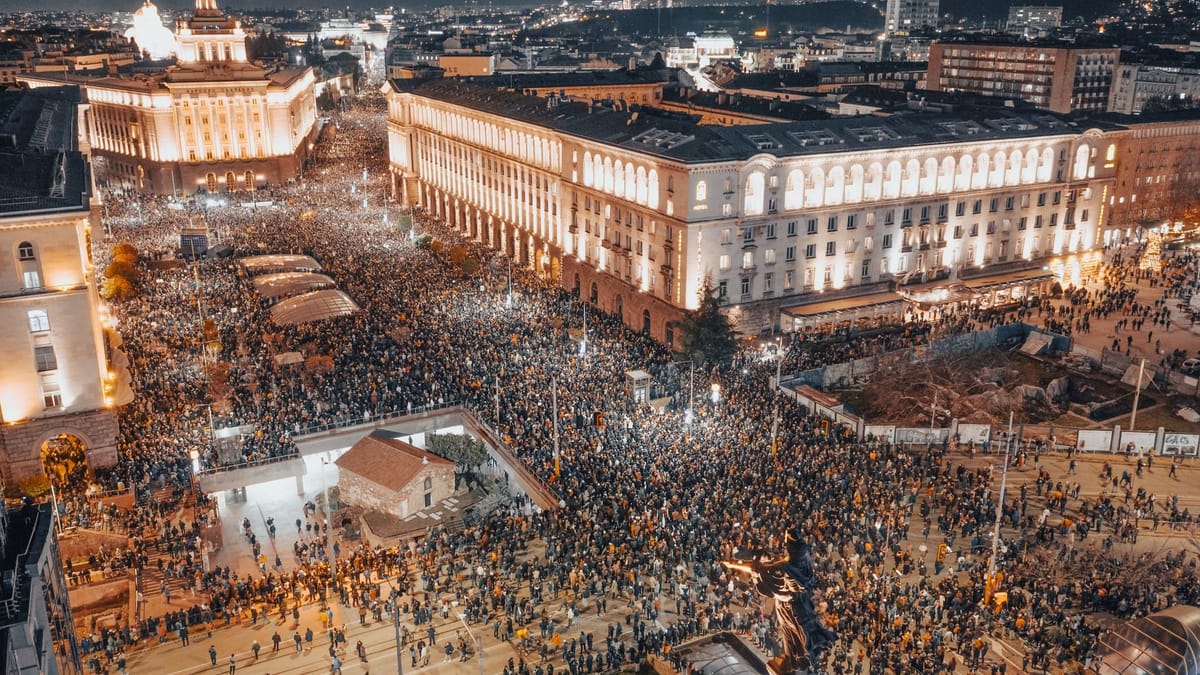
Тук нямаме такава бурна обществена реакция.
Но пък на принципа на снежната топка натрупващите се случаи на обезглавяване на журналистиката година след година доведоха до качествени изменения. За първи път миналата седмица новоизбран министър-председател, пък макар и служебен, избра за първото си програмно интервю не голям телевизионен ефир, а нишов интернет подкаст.
Гостуването на Гюров в „Бюрото на Константин Вълков“ дава ясен знак: големите политически процеси, включително и предизборните кампании, вече имат нов терен. И той е в интернет.
Електоратът е във Facebook и TikTok, не пред телевизора
Особено младите и особено негласуващите. Те познават Юксел Кадриев като поет от Instagram, а за сутрешните блокове разбират, когато откъси от тях попаднат в клиповете на „Цанов НАПРЕД и НАГОРЕ“. Те не включват телевизора, освен на Netflix, и не познават лицата и имената от телевизионните студиа. Вероятно и Косьо Вълков не познават – той също идва от преддигиталната епоха. Но завоят е ясен.
Взе го и Бойко Борисов, който досега поне не показва да е загубил природно силните си медийни инстинкти. През януари, след дълго мълчание, той даде общо четири пространни интервюта. Макар при него миксът между традиционни и нови медии да беше по-балансиран между старите брандове, като „Капитал“ и bTV, и YouTube каналите на Явор Дачков и Мартин Карбовски.
Това изместване на голямата конкуренция от телевизията към интернет не е само български феномен. По света вече е стандарт. Най-гледаните политически разговори в САЩ през последните години не са телевизионни интервюта, а подкасти. Някои от тях – като на Джо Роган – достигат аудитория, сравнима с тази на национални телевизии. Голяма част от подкастите направиха възможна безапелационната победа на Тръмп, който видя потенциал в т.нар. manosphere – общо название за онлайн общности, форуми и инфлуенсъри, които обсъждат мъжествеността, отношенията между половете и ролята на мъжете в обществото, като в тези общности често се появяват мизогиния, конспиративни идеи и радикализиране на млади мъже. Знаме на маносферата в глобален мащаб е Андрю Тейт, в местен се опитват да бъдат хора като Киро Брейка. И резултатите са налице. В глобално проучване Gen Z се оказа най-консервативното от години насам, като 30% от младите мъже смятат, че жените трябва да им се подчиняват.
Но подобни формати не са само крайнодесни. Във Великобритания The Rest Is Politics събира милиони гледания и често задава дневния ред на политическия разговор в страната.
Има ли компас в информационния океан?
С колкото повече информация разполагаме, толкова повече се давим в нея. Александър Драганов дава някои ценни съвети как да отсяваме зърното от плявата и да не ставаме жертва на собствените си или чужди конспирации.
 Александър Драганов
Роди се и нова професия – т. нар. нюзинфлуенсъри.
Хора, които се явяват нещо като продължение на журналистиката в дигиталната епоха. Понякога са бивши журналисти. Понякога просто харизматични коментатори. В много случаи аудиторията им вече е по-голяма от тази на традиционни редакции и те развиват собствена медийна екосистема, създавайки едновременно възможност и риск за журналистиката, каквато я познаваме.
Алгоритми
Подреждат какво виждаме, кога го виждаме и колко често го виждаме.
Нюзинфлуенсъри
Превръщат новините в директен, персонален канал към аудиторията.
Политици
Все по-често комуникират без журналистически посредник.
Публика
Вниманието вече се разпределя между много гласове
Журналистиката не изчезва, но губи монопола върху това кой обяснява света.
Това е криза не само на бизнес модел, а и на посредничество.
От една страна, нюзинфлуенсърите достигат до групи, които са завинаги загубени за традиционните медии. Вероятно стоят в основата на Gen Z активизма, залял площадите миналата година не само в България. За тези нови публики журналистиката не е институция, нито е система от правила и стриктни принципи за работа с информация.
Журналистиката е съдържание. Парасоциално свързване с лице, глас, профил, таг. Изискването тук не е истината или фактите.
В изследване на Pew Research потребителите очертават профила на идеалния нюзинфлуенсър така: да ми помага да разбирам актуалните събития и проблеми; да реагира бързо, когато нещо се случва; да е автентичен – разбирай, да говори от свое име или поне така да изглежда. „Да ме забавлява и да споделя моите ценности и мнения“ е важно в различна степен за 70% от анкетираните.
Сега сравнете това с ценностите на журналистическата професия и ще разберете откъде идва рискът на новия модел.
Единственото общо е целта – да информира и да разяснява социално значими процеси. При нужда – бързо. И с това приликите свършват. Докато журналистиката търси факти, тук нуждата е от споделени преживявания, мнения и ценности. Търси се общност, формирана на основата на емоционални сходства.
Мислят като мене, значи това, което ми казват, е вярно. Ако мнението ми харесва, нямам нужда от факти. Ако фактите развалят споделеното ни мнение, ще си намерим алтернативни факти. За да опазим общността.
Докато от журналистите се очаква да се стремят към обективност и дистанцираност от всички страни, да се пазят да не стават част от историята, която представят, и да се стараят отчетливо да отделят мнение от факт, от инфлуенсърите се иска персонифицирано съдържание, което да забавлява и утвърждава. Докато в журналистиката конфликтът е норма и начин на мислене, в социалните мрежи той е белег за токсичност и води до блокиране и канселиране.
Освен това, за разлика от редакциите, инфлуенсърите рядко имат процес по проверка на фактите или задължение за поправяне на грешки. И когато съдържанието се движи от алгоритми, подсилващи емоцията и конфликта, изкушението да се гони тренд, който става вайръл, вместо най-постижимата версия на истината е огромно.
Така именно нюзинфлуенсърите стават и потенциален основен източник на дезинформация. А по-тихата промяна е, че изтънялото доверие допълнително се измества от институции към личности.
В политиката това води до вълна от мачопопулизъм. В медиите – до фен бази и парцелиране на публиката на твърди ядра на принципа свой–чужд. А онези „архивни“ журналисти, които отказват да се влеят в която и да било идеологическа ниша и продължават да бъдат критични към всяка власт и всяка идеология, в крайна сметка се оказват обречени да загубят всяка публика. Защото, както видяхме и по случая „Петрохан“,
и добрите, и лошите не искат журналистика, когато не харесват новините.
Един тежък криминален случай отново и по болезнен за всички ни начин показа до каква степен държавата е абдикирала от основни свои функции, оставяйки гражданите си абсолютно уязвими: от образование, през защита на горите, до правораздаване и служби за сигурност. Когато доверието в институциите, призвани да търсят истината, практически липсва, Facebook неизбежно се превръща в министерство на истината, а три милиона следователи – в разследващи журналисти.
Водещият твърде много питаше
Кампания в подкрепа на журналистите, свалени след политически натиск.
 Тоест
Хора, които едно интервю не са вземали през живота си, се надпреварват да дават съвети на Миролюба Бенатова, Генка Шикерова и Мария Черешева:
- кои въпроси трябва да се задават;
- кога и при какви условия могат да прекъсват събеседник;
- трябва ли да се правят интервюта при незавършени разследвания;
- трябва ли да се говори с жертви на престъпления;
- кои майки имат право да говорят и кои – не.
Напоследък си мисля, че наблюдаваме как в края на земния си път журналистиката изпълнява самоотвержено своята последна обществена функция – да обедини иначе необединими обществени групи. Едните харесват Украйна, другите ходят на 3 март с руско знаме. Едните харесват гей парада, другите – парада на традиционното българско семейство. Едните искат България винаги в Европа, другите – никога срещу Русия.
Свързва ги само едно.
Че журналистите са гадове.
А „гадовете“ са малцината останали нормални журналисти, които имат комбинацията от опит, гръбнак, познания и интегритет да пазят журналистиката от фенщината. И им се занимава с това. Казвам „малцина“ и мога да ги назова поименно – не са повече от 20. Признавам си, че имам специално отношение към тях. Като към защитен вид. Защото алтернативата е Андрю Тейт или Киро Брейка.
Баланс, стандарти и етика. Това, разбира се, са много важни категории в нашата професия. И извратени до пълната им антитеза в родните ни медийни условия. Не защото не са съществени, а защото в лицето на користни играчи и/или непрофесионалисти могат да бъдат прилагани, както дяволът чете евангелието. Или, за да съм по-конкретна – както българска прокуратура делото за КТБ.
Мога да дам пример от годините ми като шеф на новините в Нова телевизия.
Когато започна разследването срещу Делян Пеевски по Глобалния закон „Магнитски“ и се появиха първите данни, че може да му бъдат наложени санкции за корупция, ръководството на телевизията имаше сериозен проблем, че отразяваме темата. Подозирам, че проблемът е бил на някого извън телевизията. Но аргументите звучаха познато. Същите аргументи, които чуваме днес по казуса „Петрохан“.
„Това е неприключило производство.“
„Защо трябва да правите интервюта на парче?“
„Защо давате думата на адвокати на обвиняеми?“ (В онзи случай – Цветан Василев, който след фалирането на КТБ вече беше готов да говори срещу бившите си ортаци.)
„Къде е другата гледна точка?“ (Пеевски тогава все още не говореше пред асансьора.)
„Защо не изчакате разследването да приключи, да отиде някой до САЩ, да прочете всички тези документи, които се цитират като основание за санкциите, и тогава да направите журналистическо разследване?“
Ако бяхме следвали тези „професионални“ препоръки, вероятно и до днес нямаше да сме споменали темата „Магнитски“ в новините. Което, подозирам, е била и целта.
Но сега виждам същите аргументи от хора, с които довчера протестирахме в защита на Мария Цънцарова и свободата на журналистиката.
През годините съм стигала до един и същ извод:
всеки защитава до кръв свободата на словото, с което е съгласен.
Докато журналистиката защитава нашата кауза, тя е необходима. Когато обаче започне да задава неудобни въпроси на „нашите“ или срещу „нашите“, изведнъж се оказва проблем. Само че свободата на медиите има нужда от защита точно тогава, когато в търсене на истината стига до неудобни и непопулярни тези.
На ежедневна база журналистиката рови в неподреденото. Осветява ъгли на споделените ни обществени килери, които са непоносими, разхвърляни и често миришат или изглеждат неприятно.
И точно тогава ни трябва – за да ни води през тези неосветени коридори, докато се прояснят силуетите на истината срещу караконджулите на фалшивите новини, пропагандата, конспирацията и обикновения информационен хаос.
Има ли надежда за надеждните новини?
„Революцията няма да я дават по телевизията.“ Гил Скот-Херън е бил наясно с това отдавна. Контекстът днес обаче е друг – за да могат да оцелеят финансово, (сравнително) надеждните медии заключват съдържанието си и така се създават информационни касти, но и паралелни реалности. От Светла Енчева.
 Светла Енчева
Може би е нужно тук да обясним какво всъщност прави журналистът.
Защо прекъсва? Защо задава въпрос по няколко пъти? Защо работи по неразкрити престъпления? Защо понякога се движи по тънкия лед между интереса на малцина и нуждата за информираност на мнозина?
В Етичния кодекс на журналистите – този, който всички обичат да цитират, но малцина са чели – има няколко основни принципа.
Първият е:
Търси фактите и ги съобщавай.
Не „Търси фактите и ако се харесват на публиката, ги съобщавай“. Не е и „Търси фактите и ако са забавни, ги публикувай“.
Вторият е:
Минимизирай вредата.
Обърнете внимание – не е „Не вреди“. Вреди с мярка. Тоест професията допуска, че в процеса на търсене на истината неизбежно може да се стигне до вреда. Нашият стандарт е да направим най-голямото възможно добро за най-голям брой хора.
Това означава, че понякога ще задаваме въпроси, които връщат събеседниците ни на места, на които те не искат да бъдат. Разбира се, с нужните защити за най-незащитените – деца, жертви на престъпления и т.н. И обратно – за хората с публична власт пространството на лична защита следва да е силно ограничено до липсващо. Но никъде етичните стандарти не ни задължават да не поемаме рискове. В името на това обществото да знае.
Аз лично винаги ще избера разговор със свидетел на престъпление пред камера – с всички произтичащи от това етични дилеми – вместо журналистика по режисирано изтекли показания от МВР. Защото истинската журналистика се прави пред очите и от името на публиката. Другото е пиар.
Разликата между пиара и журналистиката се разбира, когато ти потрябва журналист. От вида честен и безпристрастен. От Червената книга на онези, пазили се да стоят между агитките, понасяйки удари от всички страни. Изпаднали в слаба позиция, добри и лоши, свои и чужди, либерали и консерватори пак се обединяват – този път в нуждата. И започват да викат почтената журналистика. Изненадани, бившите силни разбират, че за слабите журналистика няма. Ами няма – медиите са или ваши, или са срещу вас. Ти си го избра, както е казал мъдрецът.
Този смешен плач плакаха всички – от Цветан Цветанов, през Иван Гешев, до Ахмед Доган и Цветан Василев. Последният, участвал лично в процеса по придобиването на едни медии и обезшумяването на други в силните години на КТБ, днес пише в личния си сайт, че бил цензуриран от неетични журналисти или техните редактори. Нима?
Има нещо поучително в това как всички цензори намразват цензурата, упражнявана от някой друг, след като собствената им хунта ги избута отвъд разделението свой–чужд. Мило е, но не върши работа дори и за кратковременно злорадство.
През това време в TikTok и Instagram постжурналистиката експериментира и с нов бизнес модел: директна връзка с публиката чрез абонаменти, дарения и платформи за подкрепа. Не рекламодателят, а зрителят плаща.
От една страна, това би трябвало да е добре. Американският медиен критик Ей Джей Либлинг още през 1960 г. отбелязва: „Свободата на пресата е гарантирана за онези, които притежават преса.“
Но когато читателите и зрителите станат инвеститори, и то в среда, която от години е нормализирала нагласата да третира медиите като наемници на частен капитал, тогава и капиталисти на дребно могат да започнат да си искат своето. И ако не им харесва отражението в огледалото, да пожелаят да убият този, който го държи. Или поне да спрат да си плащат абонаментите.
А на пазара оцеляват идеи, стоки и услуги, от които някой има нужда. Икономистите му викали jobs-to-be-done теория. Хората „наемат“ продукт или услуга, за да им свършат определена работа. Ако се появи по-добър (евтин, лесен, забавен) начин да се свърши същата „работа“, старият продукт изчезва.
Доскоро журналистите малко елитарно и самонадеяно смятаха, че имат запазеното място на важни и нужни на обществото.
А може би вече не.
Няма да е първата професия, която е изчезнала поради отпаднала необходимост.
Съвсем не е невъзможно да си представим, че един ден и журналистиката ще се подреди в музея на професиите – до глашатая, телефонистката и словослагателя (този, който реди металните букви в печатарството). Заместена от създателите на новинарско съдържание за тези, които си плащат за споделеност и забавление.
Announcing Cloudflare Account Abuse Protection: prevent fraudulent attacks from bots and humans
Post Syndicated from Jin-Hee Lee original https://blog.cloudflare.com/account-abuse-protection/
Today, Cloudflare is introducing a new suite of fraud prevention capabilities designed to stop account abuse before it starts. We’ve spent years empowering Cloudflare customers to protect their applications from automated attacks, but the threat landscape has evolved. The industrialization of hybrid automated-and-human abuse presents a complex security challenge to website owners. Consider, for instance, a single account that’s accessed from New York, London, and San Francisco in the same five minutes. The core question in this case is not “Is this automated?” but rather “Is this authentic?”
Website owners need the tools to stop abuse on their website, no matter who it’s coming from.
During our Birthday Week in 2024, we gifted leaked credentials detection to all customers, including everyone on a Free plan. Since then, we’ve added account takeover detection IDs as part of our bot management solution to help identify bots attacking your login pages.
Now, we’re combining these powerful tools with new ones. Disposable email check and email risk help you enforce security preferences for users who sign up with throwaway email addresses, a common tactic for fake account creation and promotion abuse, or whose emails are deemed risky based on email patterns and infrastructure. We’re also thrilled to introduce Hashed User IDs — per-domain identifiers generated by cryptographically hashing usernames — that give customers better insight into suspicious account activity and greater ability to mitigate potentially fraudulent traffic, without compromising end user privacy.
The new capabilities we’re announcing today go beyond automation, identifying abusive behavior and risky identities among human users and bots. Account Abuse Protection is available in Early Access, and any Bot Management Enterprise customer can use these features at no additional cost for a limited period, until the general availability of Cloudflare Fraud Prevention later this year. If you want to learn more about this Early Access capability, sign up here.
The barrier to entry for fraudulent behavior is dangerously low, especially with the availability of massive datasets and access to automated tools that commit account fraud at scale. Website owners aren’t just dealing with individual hackers, but industrialized fraud. Last year, we highlighted how 41% of logins across our network use leaked credentials. This number has only grown following the exposure of a database holding 16 billion records, and multiple high-profile breaches have since come to light.
What’s more, users reuse passwords across multiple platforms, meaning a single leak from years ago can still unlock a high-value retail or even a bank account today. Our leaked credential check is a free feature that checks whether a password has been leaked in a known data breach of another service or application on the Internet. This is a privacy-preserving credential checking service that helps protect our users from compromised credentials, meaning Cloudflare performs these checks without accessing or storing plaintext end user passwords. Passwords are hashed — i.e., converted into a random string of characters using a cryptographic algorithm — for the purpose of comparing them against a database of leaked credentials. If you haven’t already turned on our leaked credential check, enable it now to keep your accounts safe from easy hacks!
Access to a large database of leaked credentials is only useful if an attacker can cycle through them quickly across many sites to identify which accounts are still vulnerable due to password reuse. In our Black Friday analysis in 2024, we observed that more than 60% of traffic to login pages across our network was automated. That’s a lot of bots trying to break in.
To help customers protect their login endpoints from constant bombardment, we added account takeover (ATO)-specific detections to highlight suspicious traffic patterns. This is part of our recent focus on per-customer detections, in which we provide behavioral anomaly detection unique to each bot management customer. Today, bot management customers can see and mitigate attempted ATO attacks in their login requests directly on the Security analytics dashboard.

In the card on the left within the Security analytics dashboard, you can view and address attempted account takeover attacks.
In the last week, our ATO detections combined caught an average of 6.9 billion suspicious login attempts daily, across our network. These ATO detections, along with the many other detection mechanisms in our bot management solution, create a layered defense against ATO and other malicious automated attacks.
To discern automation, or to discern intent and identity? That is the question. Our answer: yes and yes, as both are critical layers of a robust security posture. Attackers now operate at a scale previously reserved for enterprise services: they leverage massive credential leaks, use human-powered fraud farms to spoof devices and locations, and create synthetic identities to maintain thousands — even millions — of fake accounts for promotion and platform abuse. A human being with automated tools could be draining accounts, abusing promotions, committing payment fraud, or all of the above.
Beyond that, automation is accessible like never before, particularly as users become better acquainted with using AI agents and even long-standing, “traditional” browsers move toward having agentic capabilities by default. Whether it’s a lone actor using an AI agent or a coordinated fraud campaign, the threat isn’t as simple as a single script — it can involve human intent, with automated execution.
Consider the following scenarios we’ve heard from our customers:
-
We have 1,000 new users this month, but more than half of them are fake identities who benefit from a free trial, then disappear.
-
The attacker logged in with the correct password, so how do I know that it isn’t the real user?
-
This entity is acting at human pace, and they are draining accounts.
These problems can’t be solved by only assessing automation; they require checking for authenticity and integrity. This is the gap that our dedicated fraud prevention capabilities address.
Let’s start by assessing the earliest point of potential account abuse: account creation. Fake or bulk account creation is one of the biggest topics in conversations about website fraud, as it can open the door for attackers to access an application — or even an entire business model.
Cloudflare is giving customers the tools to assess suspicious account creation at the source in two ways:
-
Disposable email check: Detect when users sign up with disposable, or throwaway, email addresses commonly used for promotion abuse and fake account creation. These disposable email services allow attackers to spin up thousands of “unique” accounts without maintaining real infrastructure, particularly unauthenticated disposable emails that provide instant access without account creation or free unlimited email aliases. Customers can use this binary field as they build rules to enforce security preferences, choosing to block all disposable emails outright, or perhaps issuing a challenge to anyone attempting to create an account with a disposable email.

-
Email risk: Cloudflare analyzes email patterns and infrastructure to provide risk tiers (low, medium, high) that customers can use in security rules. We know that not all email addresses are created equal; an address with the format
[email protected]carries different risk characteristics than[email protected]. Email risk tiers allow customers to express their tolerance for risk and friction at the point of account creation.
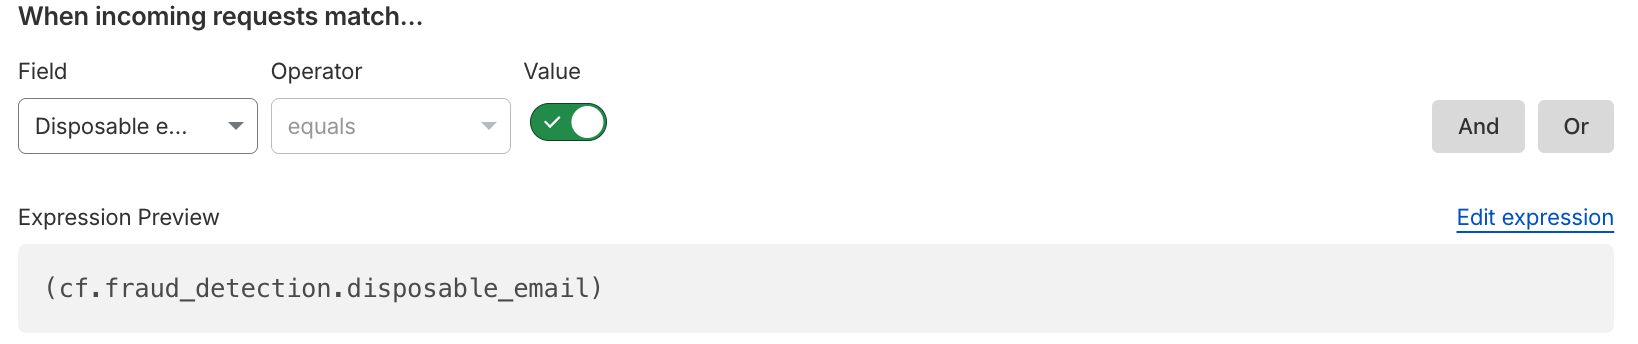
Both disposable email check and email risk are now available in security analytics and security rules, equipping website owners to protect their account creation flow. These detections address a fundamental problem: by the time an account is committing abuse, it’s already too late. The website owner has already paid acquisition costs, the fraudulent user has consumed promotional credits, and remediation requires manual review. Mitigating suspicious emails means adding the appropriate friction at signup — the moment it matters most.
Understanding patterns of abuse requires visibility: not only into the network, but of account activity. Traditionally, security has meant looking through the lens of IPs and isolated HTTP requests to spot automated activity, but website owners aren’t just thinking in terms of network signals; they are also considering their users and known accounts. That’s why we’re expanding our mitigation toolbox to match the way applications are actually structured, focusing on user-based detection of fraudulent activity.
Attackers can effortlessly rotate IPs to hide their tracks. But forcing them to repeatedly generate new, credible accounts introduces massive friction, especially when combined with account creation protections. When we look past the network layer and map fraudulent actions to a given compromised or abusive account, we can spot targeted behavior tied to a single, persistent actor and put a stop to the abuse. In this way, we’re shifting the defense strategy to the account level, instead of playing whack-a-mole with rotating IP addresses and residential proxies. This means that our customers can mitigate abusive behavior based on the way their applications separate identity.
To arm website owners with this capability, Cloudflare is releasing a Hashed User ID that customers can use in Security analytics, Security rules, and Managed Transforms. User IDs are per-domain, cryptographically hashed versions of the values in the username field, and each user ID is an encrypted, unique, and stable identifier generated for a given username on a customer application. Importantly, the actual username is not logged or stored by Cloudflare as part of this service. As with leaked credentials check and ATO detections, which identify login traffic and then encrypt credentials for comparison, we are prioritizing end user privacy while empowering our customers to take action against fraudulent behavior.
With access to Hashed User IDs, website owners can:
-
See top users: Which accounts have the most activity?
-
See when a unique user logs in from a country they usually don’t — or multiple countries in one day!
-
Mitigate traffic based on unique user, such as blocking a user with historically suspicious activity.
-
Combine fields to see when accounts are being targeted with leaked credentials.
-
See what network patterns or signals are associated with unique users.
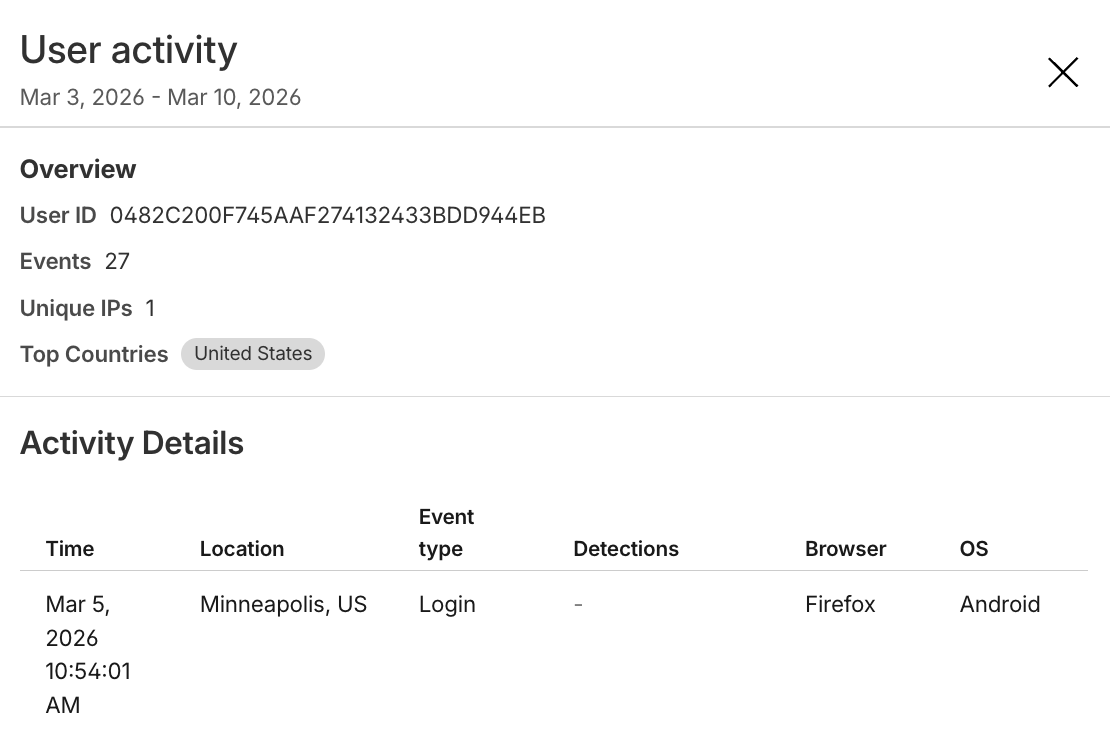
The expanded view of a single Hashed User ID within the Security analytics dashboard, showing the activity details of that unique user, including their login location and their browser.
This user-level visibility transforms how website owners can investigate and mitigate traffic. Instead of examining individual requests in isolation, our customers can see the full picture of how attackers are targeting and hiding among legitimate users.
If you want to learn more about this Early Access capability, sign up here. All Bot Management Enterprise customers are eligible to add these new Account Abuse Protection features today, and we’d love to open the conversation with any and all prospective Bot Management customers.
While bot detections will continue to answer the question of automation and intent, fraud detections delve into the question of authenticity. Together, they give website owners comprehensive tools to fight against the full spectrum of account abuse. This suite is one step in our ongoing investment to protect the entire user journey — from account creation and login to secure checkouts and the integrity of every interaction.
Enabling R8 optimization at scale with AI-assisted debugging
Post Syndicated from Grab Tech original https://engineering.grab.com/r8-optimization-at-scale-with-ai-assisted-debugging
Grab is Southeast Asia’s leading superapp, providing a suite of services that bring essential needs to users throughout the region. Its offerings include ride-hailing, food delivery, parcel delivery, mobile payments, and more. With safety, efficiency, and user-centered design at heart, Grab remains dedicated to solving everyday issues and improving the lives of millions. As our app continues to expand, we identified platform-level performance challenges that were affecting user experience across the board. In this article, we share how we successfully enabled R8 optimization for the Grab Android app, achieving significant improvements in app size, startup time, and stability through innovative AI-assisted debugging techniques.
Introduction
Since 2024, our team observed a concerning trend: Application Not Responding (ANR) rates were spiking across the Grab app. Unlike typical isolated issues, the data revealed that ANRs were happening everywhere, not confined to specific features or modules. This pattern pointed to platform-level causes, with our analysis showing strong correlations between ANRs and several factors like memory pressure (particularly when garbage collection was triggered), ad-heavy user flows, overhead from heavy use of Jetpack Compose within XML layouts, and XML views within Compose code.
The Android community had long proven that R8 optimization (beyond basic code shrinking) could deliver substantial performance gains and app size reductions. As Grab has been adopting Jetpack Compose over the last two years, Google’s Jetpack Compose performance documentation specifically recommends R8 optimization for Compose-heavy apps. This made it a natural solution for our systemic performance issues.
The challenge at scale
However, enabling R8 optimization for Grab’s Android app was far from straightforward. Our app operates at a massive scale with over 9 million lines of code and more than a hundred engineers actively working on it daily. While we had basic R8 shrinking enabled, advanced optimization had proven challenging despite multiple attempts over six years (earlier with adopting DexGuard, later with R8 optimization).
In 2022, we almost succeeded with R8 optimization after successfully rolling it out onto our early access build. We were unfortunately faced with critical roadblocks that compelled us to put the project on hold. After analyzing our previous attempts and the current project situation, we identified three fundamental challenges that had to be solved simultaneously.
This article explains how we tackled each challenge through targeted innovations, including AI-assisted debugging for slow investigation cycles, pragmatic testing strategy for validation at scale, and optimized feedback loop for rapid iteration.
Understanding R8 optimization
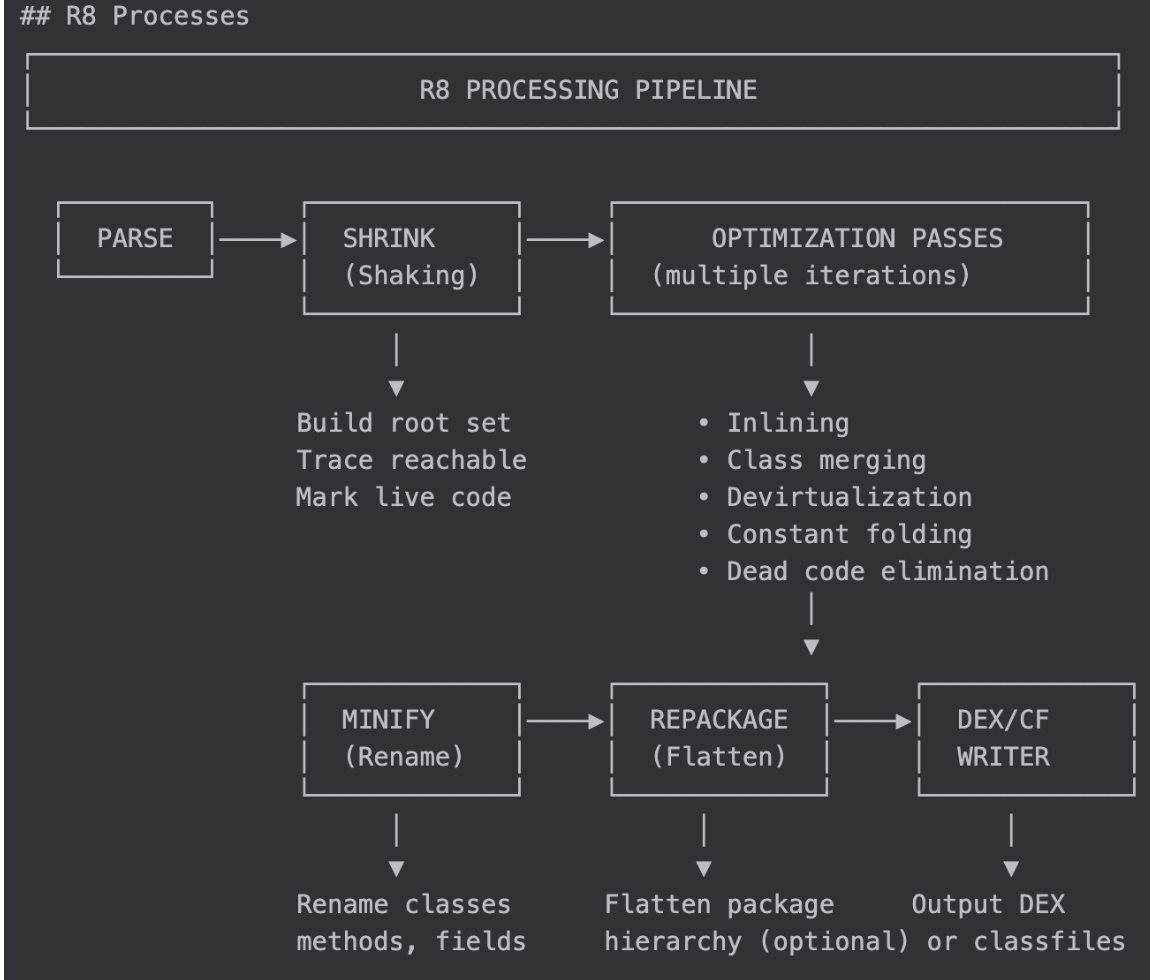
Before diving into our solution, it’s important to understand what R8 optimization actually provides beyond basic R8 shrinking.
What we had in place
With minifyEnabled=true and shrinkResources=true using proguard-android.txt, we already had:
- Tree shaking (shrink phase): Removes unused/unreachable code.
- Code minification (obfuscation): Renames classes/methods to short names.
- Resource shrinking: Removes unused XML files and drawables.
- Desugaring: Java 8+ compatibility.
What’s new with optimization
By switching to proguard-android-optimize.txt, we gained access to:
- Method inlining: Replaces method calls with actual code, reducing call overhead.
- Class merging: Makes code more compact by combining similar classes.
- Constant folding: Pre-computes constant expressions at compile time.
- Dead code elimination: More aggressive than tree shaking, removes unreachable branches.
- Devirtualization: Converts virtual calls to direct calls when possible.
These optimizations work together to improve runtime performance while significantly reducing app size.
Three core challenges
Despite R8’s clear benefits, enabling it at Grab’s scale remains hard. Lessons from prior attempts and current project context surfaced three fundamental challenges we needed to solve.
Challenge 1: Slow debugging
R8 optimization issues are notoriously difficult to debug:
- Code is obfuscated, class names become
a,b,c. - Code is modified, inlined, merged, and optimized beyond recognition.
- Stack traces are unreadable without proper mapping files when crashes occur.
- Pinpointing the root cause requires manual reverse engineering.
The challenge was compounded by limited bandwidth and high labor requirements. Most issues had to be either addressed directly or have solutions provided for other teams to fix. Manual decompilation, deobfuscation, and context gathering for each issue are inherently time-consuming, making the investigation cycle prohibitively slow.
Challenge 2: Testing at scale
R8 optimization affects every corner of the app. Unlike feature-specific changes, enabling optimization transforms how the entire codebase is compiled, inlined, and optimized. A single misconfiguration or missing keep rule can break seemingly unrelated features across different modules and Software Development Kits (SDKs).
When we first enabled R8 optimization, the impact was immediate and widespread—most of the app’s features simply stopped working correctly. This presented us with a deeper problem: not just how to test, but what kind of testing strategy would actually give us confidence to roll out to production.
In theory, R8 optimization works reliably with standard codebases that follow Google’s and the community’s best practices. However, considering the large scale of Grab’s project, legacy code patterns, reflection usage, and SDK integrations have been accumulated over the years, creating numerous edge cases.
This combination makes comprehensive testing necessary, but at our scale, it’s nearly impossible to execute due to:
- Full regression testing: Requires significant effort from all teams across the organization.
- Quality Assurance (QA) resource constraints: Exhaustive testing is impractical.
- High-quality bar: At Grab, app stability and zero runtime errors are non-negotiable standards.
This creates a catch-22: we need broad coverage because consistency can’t be guaranteed everywhere, yet the scale makes that coverage infeasible.
Challenge 3: Slow feedback
Due to the large scale of the project, compiling a build with R8 optimization enabled on a standard engineering laptop is physically impossible. This created a significant bottleneck: a slow feedback loop where every experimental change required a remote Continuous Integration (CI) build to verify, with each R8-optimized build taking up to 2 hours to complete.
Additionally, R8 treats debug and release build types differently. At Grab, we have a QA build for QA testing. This is a debug build type with R8 enabled, pointed to our staging environment. We had to ensure this QA build’s R8 configuration matched our production build exactly. This alignment was critical for catching R8-specific issues during QA testing that would actually reflect production behavior.
Our three-innovation solution
To overcome these three fundamental challenges, we developed a comprehensive strategy centered on targeted innovations that addressed each bottleneck:
Innovation 1: AI-assisted debugging
Solving challenge 1:
How do we speed up the investigation of R8 issues in obfuscated, optimized code at scale? The answer is in emerging AI technology that wasn’t available during our previous attempts.
The AI context at Grab:
Unlike 2022 and earlier attempts, the landscape had changed dramatically. After the LLM explosion, Grab proactively promoted Large Language Model (LLM) usage to boost engineering productivity. Over the past two years, Grab has dedicated 1 to 2 months annually for engineers to learn how to use AI efficiently. This investment in AI literacy became crucial for this project.
This year, my team gained experience building Model Context Protocol (MCP) servers and identified an opportunity: applying this technology to solve the R8 debugging challenge.
Our solution:
At Grab, we use GitLab for Continuous Integration and Continuous Delivery (CI/CD). To tackle R8 debugging bottlenecks, we built a comprehensive solution combining:
Build MCP tools: Eliminate manual reverse engineering
- Automatic Android Application Package (APK) decompilation: Parse and decompile APKs.
- Stack trace deobfuscation: Automatically map obfuscated traces to source code.
- Class/method context fetching: Pull relevant decompiled code sections for analysis.
AI and CI pipeline workflow:
We developed a systematic two-phase approach for investigating and fixing each runtime issue, combining AI assistance with parallel testing. The phase breakdown is as follows:
Phase 1: MCP server tools for debugging
- Detect runtime issue: From End-to-End (E2E) tests, QA testing, or crash reports.
- MCP tool orchestrates APK analysis: Coordinates decompilation tools for reverse engineering.
- MCP tool provides decompiled code context: Pulls and decompiles problematic code sections.
- Engineer and AI analysis: The engineer uses AI assistance to analyze the decompiled code context and note down multiple solution approaches.
Phase 2: GitLab CI integration
We leveraged the GitLab CLI tool (glab) and instructed AI to use it for interacting with our CI pipeline:
- AI creates multiple Merge Requests (MRs): Using
glabCLI, AI creates merge requests for different solution approaches from Phase 1, each triggering CI compilation. - Track progress: Maintain an MD file as the source of truth for the investigation, containing all notes about the issue (root cause analysis, test cases, test branches, CI build status).
- AI fetches APK from CI: Using
glabCLI to retrieve built APKs from completed CI pipelines. - Verify: Ask AI to use Android Debug Bridge (ADB) to install APK, then manually test the fix.
- Iterate: If issues remain, loop back to step 2 for further analysis.
Why this worked:
Our approach functions as an AI assistant that:
- Decodes the obfuscated code automatically.
- Finds the relevant code sections without manual searching.
- Suggests multiple solutions based on the context provided by the MCP tools.
- Creates multiple test branches simultaneously and runs parallel CI builds to test different approaches.
- Tracks everything to ensure no progress is lost on complex investigations.
Instead of testing solutions one-by-one (waiting 2 hours per build), AI creates multiple MRs in parallel, dramatically accelerating the verification process. Engineers focus on making decisions about which solutions to pursue while the AI handles both the mechanical work and the parallel experimentation.
The impact: Accelerating investigation
While investigating a single R8 issue might still take days, our MCP tools dramatically accelerated critical investigation tasks. Manual tasks that previously took hours for decompilation, deobfuscation, and context gathering were reduced to minutes. Additionally, AI assistance significantly sped up the analysis phase, helping engineers quickly identify patterns, suggest solutions, and explore multiple approaches in parallel, both analytically and through simultaneous CI builds, further accelerating the overall investigation process.
Innovation 2: Pragmatic testing strategy
Solving challenge 2:
How do we do testing at scale? How do we validate R8 optimization across a mature codebase containing more than seven million lines of code when comprehensive testing is necessary but impossible? Our solution came from a critical insight about R8 issues at scale.
Testing approaches that don’t work with R8:
- Unit tests: Run on Java Virtual Machine (JVM), while R8 optimizations affect Android Runtime behavior – fundamentally different environments.
- UI tests with R8: Community solutions exist as Gradle plugins, but our tests run on Bazel – complex setup and reliability concerns.
Key insight:
From our experience, R8 issues tend to share similar root causes across the codebase. Legacy patterns like reflection usage, parser implementations, and dynamic class loading follow consistent patterns within a large codebase. This insight led to two key advantages:
- Fix one, help many: Fixing one place often resolves issues in others.
- Pattern recognition: Once we identify a pattern, we can search the codebase to find similar issues instead of waiting for QA to discover them.
If we could identify and fix these pattern-based issues, we could address many problems without testing every corner of the app. We decided to start with critical paths and expand from there. This “ripple effect” strategy began at the center with the most important flows, then expanded by identifying common root causes and similar patterns across the codebase.
We designed a progressive risk-based validation strategy:
-
Stage 1: E2E tests – pattern discovery phase: Fortunately, we had existing E2E tests covering most critical paths in the project, and they could be executed with R8 optimization enabled. Initially, all E2E tests failed after enabling optimization. This became our opportunity for pattern discovery. We systematically fixed issues and applied our pattern-based approach to resolve similar problems across the project.
-
Stage 2: QA smoke tests – coverage expansion: After E2E tests stabilized, we requested our QA team to run smoke tests on critical flows, especially those not covered by E2E automation. This caught additional edge cases and validated that the pattern-based fixes we applied were effective across different user journeys. We fixed any issues that appeared during this phase.
-
Stage 3: Daily QA build enablement – real-world integration: After confirming stability in controlled testing, we made a significant decision to enable R8 optimization in our daily QA build (the build our QA team uses for daily feature testing). This integrated R8 optimization into the normal development workflow without requiring additional testing effort.
-
Stage 4: Regression testing and Grab Early Access (GEA) – parallel production-scale validation: After confirming stability in daily QA builds, we moved to production-scale validation with two parallel tracks. Every release at Grab includes regression testing covering all critical paths and new features. With R8 optimization now enabled in the QA build, we ran regression tests using this build for a few weeks, providing sustained validation across multiple release cycles. One week after regression testing, we rolled out to GEA, Grab’s internal production release channel for Grab employees and partners. While GEA users typically receive features one week before general production rollout, for this R8 optimization project, we extended the GEA phase to 2 weeks, given the significance of the change. With hundreds of daily active users using the app in real-world production conditions during this extended period, we encountered only one remaining R8 issue during the GEA phase. This combination of regression testing and real-world GEA production usage gave us the confidence needed before full production rollout.
Pattern-based issue resolution:
Throughout these validation phases, when we identified R8 issues, we followed a systematic pattern-based resolution process.
- Identify the issue: Catch the failure through E2E, QA, or monitoring.
- Find the pattern: Analyze the root cause to identify if it’s a common pattern across the codebase.
- Detect similar instances: Search the entire codebase to find the same pattern across different modules and the internal SDKs.
- Coordinate fixes: Create tickets requesting teams to modify their code to prevent the same issue in their modules.
This approach required cross-team coordination for fixing, but critically, not for testing. The difference is significant: asking teams to fix identified issues in their modules is much more scalable than requiring all teams to perform comprehensive testing upfront.
Production rollout results:
When we made it to production, only one issue escaped to production. Notably, we had actually detected this issue through our pattern-based approach during testing and created a ticket for the responsible team to fix it. However, with ongoing daily development, the team missed one instance when implementing the fix, which caused the production issue.
This demonstrates that while our testing strategy worked effectively, human coordination challenges can still occur at scale. With a project of this scale, having only one small production issue is considered a highly successful rollout.
This approach transformed an “impossible” comprehensive testing problem into a manageable, systematic validation process, reducing what would have been months of coordinated testing effort to days, proving that a smart strategy can overcome resource constraints.
Innovation 3: Optimized feedback loop
Solving challenge 3:
The slow feedback challenge—2-hour CI builds and QA configuration misalignment—created a bottleneck for R8 debugging. We addressed this through a comprehensive infrastructure strategy targeting these critical areas:
Remote compilation to enable local build and fast feedback loop:
At Grab, we used to use Mainframer for remote execution to handle slow performance on local Gradle builds. However, since migrating to Bazel (only for the debug build without R8 enabled), we removed the large-scale Mainframer setup for every engineer. From that experience, to tackle the local compilation blocker for R8 builds, we decided to deploy a new Mainframer setup, a much smaller one with one powerful Amazon Elastic Compute Cloud (EC2) instance, serving as a solution for local compilation in a short time.
This targeted deployment transformed physically impossible local R8 builds into a manageable remote process, enabling engineers to test R8 changes without requiring powerful local hardware.
The performance improvement was substantial: from up to 2 hours in CI to around 1 hour with Mainframer—a ~50% reduction that enabled rapid iteration cycles essential for R8 debugging.
QA build configuration alignment:
We eliminated the critical gap between QA and production R8 behavior by aligning build configurations exactly. The key change was setting debuggable = false for QA builds while maintaining the environment configuration.
buildTypes {
    debug {
        if (isQaBuild()) {
            minifyEnabled true
            shrinkResources true
            debuggable false
            buildConfigField 'boolean', 'DEBUG', 'true'
            ...
        }
    }
}
From our understanding, R8 applies different optimization levels based on the debuggable flag, with more aggressive optimizations when debuggable=false. This ensured our QA testing reflected actual production R8 processing. We preserved DEBUG = true to maintain staging environment routing while achieving R8 parity.
This infrastructure foundation was essential, providing faster feedback loops that accelerated verification and investigation, while the QA build configuration matching production exactly was critical for catching real production issues during testing.
A lucky break
Perhaps most surprising: the R8 flakiness issue that blocked us in 2022 (Issue #240077160) appears to have been resolved by the R8 team. We encountered no build determinism issues during this attempt, which significantly smoothed our path to production.
Results
After ~10 weeks of systematic implementation led by one engineer collaborating with multiple teams across the organization, we achieved substantial improvements using Android Gradle Plugin 8.6.1 with R8 version 8.6.39:
- Stability: Around 25% reduction in ANR rates.
- App size: Reduced by 21.6MB (16% decrease) in download size on our reference device (zipped APK).
- Performance: Nearly 27% improvement in startup time. After enabling R8 optimization, we saw ~12% app startup improvement. However, during our analysis, we discovered that our existing baseline and startup profiles implementation was incorrect. After proper implementation, the combination of R8 optimization plus the corrected profiles delivered the full 27% improvement.
These results exceeded our initial targets and validated the significant effort required to enable R8 optimization at scale.
What’s next
Our journey doesn’t end here. We’re exploring several areas for continued optimization:
- R8 full mode: More extreme/aggressive optimization than the current mode for additional performance benefits.
- Revisit R8 keep rules: Clean up unnecessary rules that prevent optimization, and implement a governance solution to guardrail R8 rules in our pre-merge CI pipeline.
- Dead code removal for experiment framework: We discovered a solution to help R8 understand our experiment framework flags and remove dead branches for fully turned-off features.
Conclusion
Enabling R8 optimization for the Grab Android app at scale required innovation beyond traditional debugging approaches. By combining AI-assisted debugging, pragmatic testing strategies, and infrastructure investment, we overcame challenges that had blocked previous attempts for many years.
For other teams considering R8 optimization at scale: the journey is challenging, but the results speak for themselves. With the right tools, strategy, and team collaboration, it’s achievable even for the largest codebases.
Join us
Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors. Serving over 900 cities in eight Southeast Asian countries: Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam. Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. We operate supermarkets in Malaysia under Jaya Grocer and Everrise, which enables us to bring the convenience of on-demand grocery delivery to more consumers in the country. As part of our financial services offerings, we also provide digital banking services through GXS Bank in Singapore and GXBank in Malaysia. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line. We aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.
Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!
[$] LWN.net Weekly Edition for March 12, 2026
Post Syndicated from jzb original https://lwn.net/Articles/1061465/
Inside this week’s LWN.net Weekly Edition:
- Front: Chardet; Linux and age verification; Debian AI; Python lazy imports; Python type-system PEP; PQC HTTPS certificates; MGLRU; Fedora strategy.
- Briefs: LLM vulnerability; NTP security; OpenWrt 25.12.0; SUSE sale; Buildroot 2026.02; digiKam 9.0.0; Rust 1.94.0; Quotes; …
- Announcements: Newsletters, conferences, security updates, patches, and more.
Why Hegseth Has Lasted in the Trump Administration
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/ZTI9DQuCiGs
Jeffrey Goldberg: Hegseth Acts Like ‘Movie Version of Patton’
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/TTzn4G_8Hag
Beto O’Rourke: Texas Will Soon Be Necessary for Democrats to Win the White House
Post Syndicated from The Atlantic original https://www.youtube.com/shorts/TpXHNbglHJ4
[$] California’s Digital Age Assurance Act and Linux distributions
Post Syndicated from jzb original https://lwn.net/Articles/1062112/
A recently enacted law in California imposes an age-verification requirement on
operating-system providers beginning next year. The language of the Digital
Age Assurance Act does not restrict its requirements to proprietary or commercial
operating systems; projects like Debian, FreeBSD, Fedora, and others seem to be on
the hook just as much as Apple or Microsoft. There is some hope that the law will be
amended, but there is no guarantee that it will be. This means that the developer
communities behind Linux distributions are having to discuss whether and how to
comply with the law with little time and even less legal guidance.
Rapid7 Detection Coverage for Iran-Linked Cyber Activity
Post Syndicated from Rapid7 Labs original https://www.rapid7.com/blog/post/tr-detection-coverage-iran-linked-cyber-activity
The tension arising out of the conflict in Iran is beginning to show signs of expanding beyond a strictly regional crisis. Following our recent published advisories, this communication is intended to outline and summarize the detection and enrichment coverage available to Rapid7 customers, broadly assess the macro cyber threat landscape, and demonstrate the specific actions undertaken within the Rapid7 portfolio to assure our customers of the protection they receive and can expect moving forward. For a research-driven companion piece from Rapid7 Labs, dive into Iran’s Cyber Playbook in the Escalating Regional Conflict.
Tracking the campaigns associated with the current conflict
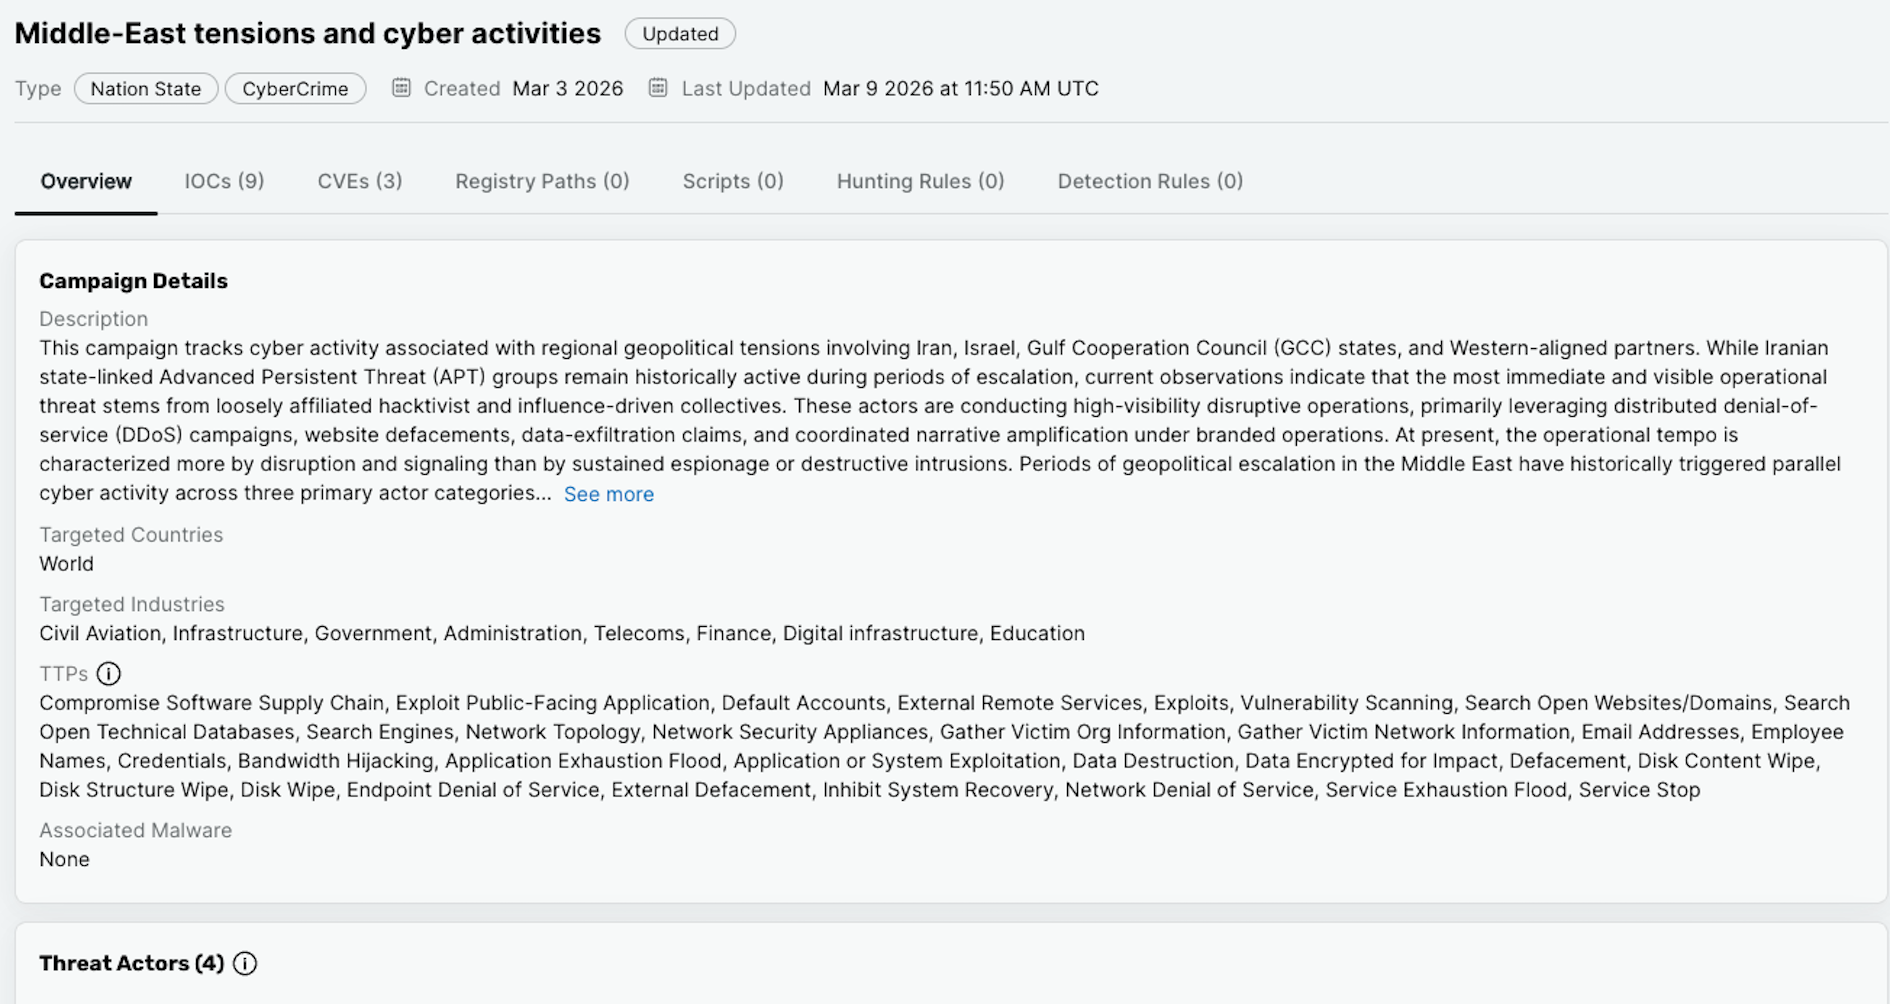
There exists a number of threat campaigns (both directly and indirectly) associated with groups associated with Iranian APT actors. In order to track details of these campaigns, any relevant indicators of compromise will be made available within Intelligence Hub.
⠀
As additional intelligence is identified and verified this campaign (and any others) will be incorporated and made available both within the detection stack across the Rapid7 portfolio, but equally for enrichment purposes within Intelligence Hub.
Hacktivist activity and Digital Risk Protection (DRP) coverage
Since the regional military escalations began in late February 2026, Rapid7 Labs has tracked a significant and ongoing spike in retaliatory cyber activity targeting regional and Western infrastructure. What we’re seeing falls into two broad buckets. The first is state-directed operations, primarily espionage and data exfiltration, carried out by actors like:
-
MuddyWater/Seedworm (MOIS)
-
CyberAv3ngers (IRGC)
-
The Handala persona (assessed as being maintained by Void Manticore under MOIS direction).
The second is a much noisier layer of hacktivist activity, stemming from groups that lack sophistication but generate outsized visibility through DDoS campaigns and public breach claims. These groups include:
-
Keymous+
-
DieNet
-
NoName057(16).
A major theme across this escalation is fabrication. Many of the breach claims circulating on Telegram and dark web forums are exaggerated or outright fake. Threat actors, especially on the hacktivist side, are recycling old leaked datasets, overstating their access, and running what amount to psychological operations aimed at causing panic and reputational damage. That said, where state-directed actors are involved, legitimate data theft is a real concern, and there is a strong likelihood that stolen material will be weaponized publicly and quickly.
Rapid7’s Digital Risk Protection platform is purpose-built to cover exactly these kinds of threats. Here is how our coverage maps to the current activity:
-
Dark web and forum monitoring — The coordination and announcements driving these campaigns are happening across Telegram, X (formerly Twitter), and dark web leak sites. DRP continuously monitors clear, deep, and dark web sources, with proprietary crawlers, inspecting tens of millions of pages. This gives us visibility into restricted forums and early warning when campaigns begin targeting specific organizations or sectors.
-
Data leakage detection and claim verification — With so many unsubstantiated breach claims in circulation, the ability to quickly distinguish real exposures from fabricated ones is critical. DRP monitors threat actor dumps and leak sites for exposed company assets and correlates what it finds against each customer’s digital footprint, giving organizations a clear answer on whether a claimed breach actually affects them.
-
Brand security and phishing defense — Threat actors are exploiting public confusion to register lookalike domains, clone websites, and create impersonation profiles on social media. DRP identifies these phishing and impersonation threats and supports the takedown of the attacker’s infrastructure.
-
Analyst-verified intelligence — Our threat intelligence analysts investigate and triage what surfaces through the platform to ensure customers receive only intelligence that has been verified and is actionable. When a real compromise or data exposure is confirmed, our team works directly with the affected organization to assess the impact and support remediation.
CVE intelligence
To fuel the data leak and psychological operations discussed above, state-directed actors like MuddyWater and Void Manticore are actively weaponizing recently disclosed, high-impact vulnerabilities. Rather than focusing on a single product, these APTs are broadly targeting a combination of internet-facing edge devices, enterprise management infrastructure, and client productivity software to gain their initial foothold.
The vulnerabilities being leveraged in these campaigns all provide either authentication bypass or remote code execution, giving attackers a direct path into the environment. Once inside, the goal is the same every time: establish persistence and get data out. As noted above, any legitimate data stolen during these intrusions is highly likely to be handed off to hacktivist personas and weaponized publicly to support the broader disinformation campaigns.
The following CVEs have been identified as actively exploited or assessed as high-priority targets in the current threat environment:
-
CVE-2026-1281
-
Description: A critical command injection vulnerability in Ivanti Endpoint Manager Mobile (EPMM) that grants unauthenticated attackers root-level remote code execution. This has been leveraged as a zero-day vulnerability to compromise mobile endpoint management environments.
Tied to: MuddyWater (MOIS) -
Metasploit Module: https://github.com/rapid7/metasploit-framework/pull/20932
-
CVE-2024-4577
-
Description: A critical OS command injection vulnerability in PHP running in CGI mode on Windows. By exploiting Windows “Best-Fit” encoding behaviors, attackers can bypass escape mechanisms and execute arbitrary code on the host server.
Tied to: Void Manticore (the MOIS-affiliated actor that maintains the Handala hacktivist persona) -
Metasploit Module: https://github.com/rapid7/metasploit-framework/pull/19247
-
CVE-2025-32433
-
Description: A pre-authentication remote command execution (RCE) flaw in Erlang-based SSH servers. Threat actors can execute arbitrary root commands by sending specially crafted SSH packets, bypassing authentication entirely.
-
Metasploit Module: https://www.rapid7.com/db/modules/exploit/linux/ssh/ssh_erlangotp_rce/
-
CVE-2025-52691
-
Description: An unauthenticated file upload flaw in SmarterTools SmarterMail. Attackers exploit a path traversal weakness via the guid variable to drop malicious files, such as webshells or malicious cron jobs.
-
Metasploit Module: https://github.com/rapid7/metasploit-framework/pull/20866
-
CVE-2025-9316
-
Description: An unauthenticated session bypass vulnerability impacting N-able N-Central. Attackers frequently chain this with an XML External Entity (XXE) vulnerability to read highly sensitive local configuration and backup files from the host infrastructure.
-
Metasploit Module: https://github.com/rapid7/metasploit-framework/pull/20713
-
CVE-2026-21514
-
Description: A security feature bypass vulnerability in Microsoft Word that allows an unauthorized attacker to bypass Object Linking & Embedding (OLE) mitigations locally. Exploitation requires user interaction to open a maliciously crafted document.
-
Rapid7 Coverage: Analyzed extensively in Rapid7’s Patch Tuesday – February 2026 blog post and prioritized for customer patching due to active exploitation
Detection and Response for Rapid7 customers
Rapid7’s Threat Hunting team has been actively hunting for activity related to Iranian actors since the regional conflict began. We are utilizing threat intelligence related to new indicators of compromise and known tactics, techniques, and procedures to conduct these hunts. If we have validated findings, the MDR SOC will investigate and communicate the details of findings using the standard notification processes.
Additional reading from Rapid7 Labs: Iran’s Cyber Playbook in the Escalating Regional Conflict
Iran’s Cyber Playbook in the Escalating Regional Conflict
Post Syndicated from Rapid7 Labs original https://www.rapid7.com/blog/post/tr-iran-cyber-playbook-escalating-regional-conflict
Following our recent published advisories, this publication is intended to outline a summary of the cyber activities associated with the tension. Based on the available information, we believe the conflict is beginning to show signs of expanding beyond a strictly regional crisis. Initial threat reporting pointed to a measurable increase in cyber activity linked to the crisis predominantly focused on hacktivist mobilization, with reports of phishing campaigns, and claims of data theft and disruptive operations. For a companion piece focused around our customers, dive into Rapid7 Detection Coverage for Iran-Linked Cyber Activity.
Cyber activity by groups associated with Iran and their affiliated ecosystems have begun to surface. Much of the visible activity currently appears to have limited immediate operational impact as it consists primarily of website defacements, distributed denial-of-service (DDoS) attacks, coordinated messaging campaigns, phishing attempts, and reconnaissance against exposed digital infrastructure. While these incidents may appear opportunistic or symbolic, historical patterns of such behavior suggest that this activity can represent early-stage signaling, pressure, and preparatory shaping operations rather than isolated disruption.
Iran’s cyber ecosystem operates through a layered structure that includes state-linked advanced persistent threat (APT) groups, proxy actors, hacktivist personas, and sympathetic foreign collectives. Even when not centrally coordinated, these actors often converge on the same narratives and target sets during geopolitical crises, enabling simultaneous visible disruption and covert intelligence-driven intrusion activity. As the conflict evolves, this ecosystem provides a scalable and deniable tool for retaliation that can gradually intensify.
It is very likely that the cyber risk will widen accordingly as the current conflict continues. Governments and organizations located in regions hosting U.S. military infrastructure or closely aligned with U.S. and Israeli positions may face increased exposure, particularly across sectors such as logistics, critical infrastructure, public administration, energy, and telecommunications.
Strategic context and operational trends
Iran does not operate according to a single publicly articulated cyberwarfare doctrine. Instead, its cyber strategy has evolved pragmatically as part of the country’s broader asymmetric security model. Since 2010, there has been an expansion of its cyber capabilities as instruments for intelligence gathering, internal control, retaliation, coercive messaging, and regional influence. Cyber operations are therefore best understood not as a separate military domain with a fully transparent doctrine, but as an adaptable component of the regime’s survival and strategic competition against outsiders.
Broadly speaking, Iranian cyber activity tends to serve three overlapping strategic objectives. The first is regime security and domestic control, in which cyber tools support surveillance, information control, and disruption of dissident or opposition networks. The second is strategic intelligence collection, in which state-linked actors target governments, defense organizations, technology providers, telecommunications firms, and critical infrastructure to gather political, military, and economic intelligence. The third is coercive signaling and regional influence, in which cyber operations impose costs on adversaries, shape perceptions, and demonstrate retaliatory capability while remaining below the threshold of overt interstate war.
A key feature of this regime’s approach is the development of long-term access. Iranian APT groups often conduct sustained intrusion campaigns focused not only on immediate collection but also on access persistence, credential harvesting, and network familiarity. In a crisis environment, these pre-existing footholds can become strategically important, supporting either intelligence collection or later disruptive operations. This is one reason current low-visibility intrusions deserve as much analytical attention as public hacktivist claims. The visible DDoS or defacement campaign may dominate headlines, but the more significant strategic risk often lies in covert access established inside other targets.
Another defining feature of Iran’s cyber strategy is its layered operational model. State-linked APT groups frequently operate alongside contractors, proxies, persona-driven influence actors, and hacktivist collectives. This structure offers several advantages: it creates deniability, increases operational tempo; broadens the range of possible targets; and allows Iran-aligned ecosystems to combine disruptive spectacle with intelligence-driven depth. During periods of heightened tension, this blended model enables visible pressure operations to coexist with quieter espionage or pre-positioning campaigns. Current reporting on the conflict strongly supports this interpretation, with activist and proxy campaigns surging in parallel to concern over state-linked phishing, malware, wipers, and infrastructure-focused targeting.
Iran’s threat actor landscape
State sponsored
Iran’s cyber capabilities are distributed across a hybrid ecosystem of state institutions, intelligence services, military structures, and semi-official operators. Rather than relying on a single centralized cyber command, Tehran appears to allocate responsibilities across different organs, primarily the Islamic Revolutionary Guard Corps and the Ministry of Intelligence and Security, with support from contractors, front entities, and affiliated personas. Strategic coordination of the cyber domain is overseen by the Supreme Council of Cyberspace, while operational activities are carried out through a mix of official and semi-official channels.
IRGC-linked actors
The Islamic Revolution Guard Corp (IRGC) maintains one of Iran’s most visible offensive cyber capabilities and has been associated with cyber espionage, influence operations, credential theft, and politically aligned disruptive activity. Among the principal IRGC-linked actors are APT35 (also known as Charming Kitten or Mint Sandstorm), which has long conducted spear-phishing and credential-harvesting operations against diplomats, journalists, researchers, and policy communities; APT42 is an actor particularly associated with surveillance and social engineering targeting dissidents, activists, journalists, and policy experts. Cotton Sandstorm (also known as Holy Souls and Emennet Pasargad), meanwhile, has been linked to both espionage and influence-oriented operations targeting regional adversaries and Western institutions. Recent reporting also highlights continued concern around malware associated with this broader actor set, including infostealing and espionage tooling used in phishing-led operations.
MOIS-linked actors
The Ministry of Intelligence and Security (MOIS) operates parallel cyber capabilities that tend to emphasize intelligence collection, long-term access, and strategic espionage. The most prominent groups in this cluster include MuddyWater and OilRig (also known as APT34). CISA has previously described MuddyWater as an Iranian government-sponsored actor conducting cyber espionage and malicious cyber operations across multiple sectors, while current reporting continues to place the group among the most operationally relevant Iranian state-linked threats in the present crisis environment. OilRig remains a longstanding espionage actor focused on governments, financial institutions, energy entities, and other strategic organizations.
These actors illustrate Iran’s distributed cyber-operational model: Intelligence-driven access development, influence, psychological pressure, and opportunistic disruptive action are not separate lines of effort but parts of a broader strategic continuum.
Parallel hacktivist and proxies
Beginning in June 2025, a noticeable surge in hacktivist and proxy cyber activity accompanied the broader escalation of tensions in the Middle East. This reflects a recurring pattern observed during previous geopolitical crises, in which ideologically aligned non-state cyber actors mobilize alongside, or in parallel with, state-linked cyber operations. In the current confrontation, this dynamic has again expanded the cyber landscape beyond traditional state-directed espionage or sabotage.
By early March 2026, several dozen hacktivists or proxy collectives emerged related to the conflict. These groups vary significantly in capability and reliability. Some focus on distributed denial-of-service (DDoS) attacks, while others conduct website defacements or hack-and-leak campaigns. Some primarily amplify claims of compromise that are exaggerated or only partially verifiable. Their significance, therefore, lies less in technical sophistication than in the cumulative pressure they place on defenders and the broader information environment.
In crisis situations, this activity can produce strategic effects. Numerous low-impact incidents can consume defensive resources, complicate attribution, and obscure more sophisticated intrusions occurring simultaneously. Hacktivist campaigns may therefore function as distractions, signals, or psychological pressure while more capable actors pursue quieter access to high-value networks. For this reason, the analytical distinction between advanced persistent threat (APT) activity and hacktivism can become blurred during periods of geopolitical confrontation.
Several collectives active in the current environment publicly position themselves as ideologically aligned with Iran or with members of the so-called “Axis of Resistance.” Among the more visible groups are Handala Hack Team, Dienet, FAD Team, APT IRAN, Cyber Islamic Resistance, and Fatimion cyber team. These actors frequently frame their operations as retaliatory cyber campaigns targeting Israeli, Western, or allied regional entities, claiming responsibility for activities such as website defacements, DDoS attacks, and hack-and-leak operations targeting mainly government, telecommunications, energy, and financial entities. Although many claims remain difficult to verify independently, their messaging strategy often emphasizes their psychological and reputational impact.
In parallel, several pro-Russia hacktivist groups have also engaged in operations linked to the confrontation, including NoName057(16), Sever Killer, and Russian Legion. These groups typically conduct large-scale DDoS campaigns targeting government portals, financial services, and transportation or telecommunications infrastructure in states perceived as supporting Israel or broader Western policy positions. Their participation illustrates how regional conflicts can attract cyber actors from outside the immediate theater when ideological alignment or strategic narratives converge.
Cyber activities linked to the ongoing conflict
Iranian APT group operations
Beyond the highly visible hacktivist activity circulating on social media, defacement platforms, and Telegram channels, a quieter but more strategically significant layer of cyber operations is unfolding through Iranian state-linked APT groups. These operations appear ongoing and aligned with broader geopolitical objectives tied to the current conflict environment.
Recent threat reporting indicates continued operations by the Iranian APT group, MuddyWater, which is widely assessed to be linked to MOIS. Since at least early February 2026, reporting has suggested potential compromises or attempted intrusions targeting organizations associated with the United States and allied interests.
According to public reporting, activity linked to the group was reportedly observed within the networks of a United States–based bank, a United States airport, a nonprofit organization operating across the United States and Canada, and a software company with operations in Israel. In several of these incidents, threat actors reportedly deployed a previously undocumented backdoor known as Dindoor, suggesting a coordinated, ongoing campaign rather than isolated compromise events.
Hacktivist and proxy disruption activities
The most visible form of cyber activity so far remains hacktivist and proxy-led disruption.
DDoS attacks are among the most common tactics employed by hacktivist groups. Pro-Russia groups such as NoName057(16) and Server Killer, along with other pro-Iran collectives affiliated with them, have been linked to waves of coordinated DDoS attacks against Israel, Qatar, Bahrain, and other politically symbolic targets. These attacks are generally inexpensive and cause only short-term technical damage, but they remain strategically useful because they disrupt public services, tie up defense resources, generate media coverage, and fuel the narrative of a sustained cyber response.
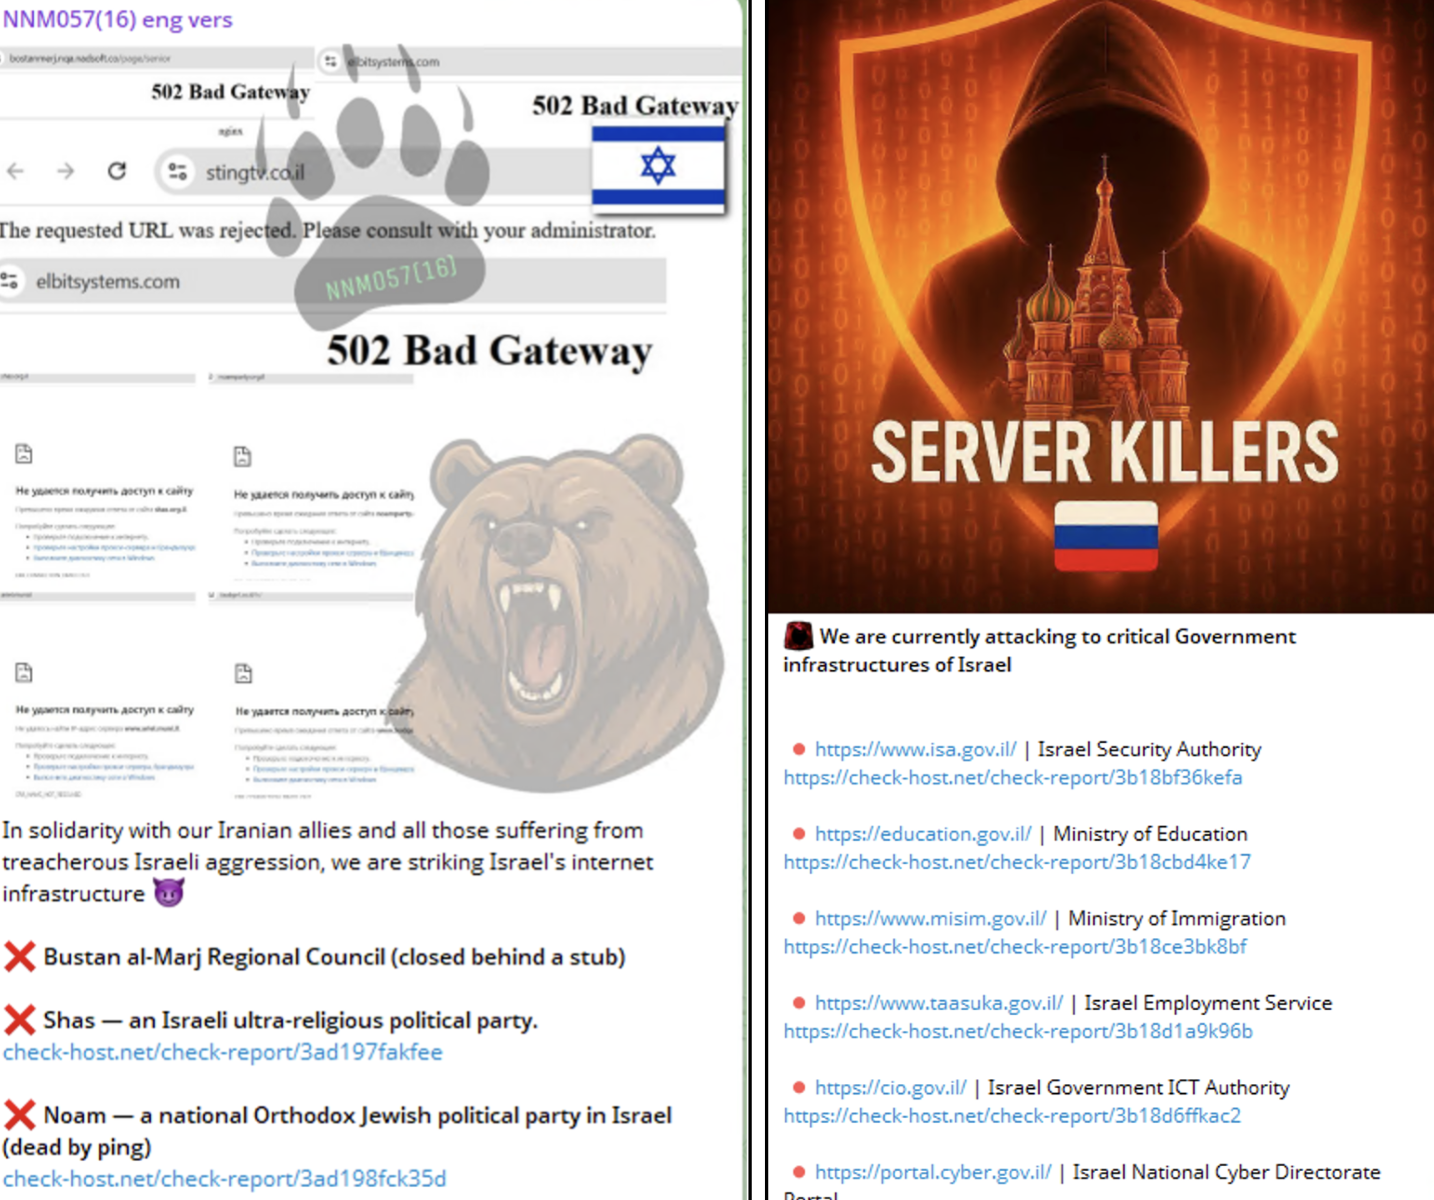
⠀
Website defacement also remains a common tactic. Groups such as FAD Team, 313, and Cyber Islamic Resistance have been associated with claims of attacks on several websites. Although defacements are technically simple to execute, they remain analytically significant: They are highly visible, rapidly disseminated, and psychologically impactful, often creating an exaggerated perception of widespread systemic compromise.
Data breaches represent a far more significant dimension of cyber operations. The Iranian-aligned group Handala, in particular, continues to blend political messaging with claims of data theft and the selective release of allegedly compromised information. The group recently asserted that it had infiltrated a Saudi energy company and exfiltrated internal documents, framing the operation as a combination of data exfiltration, coercive pressure, and psychological warfare targeting the energy sector. Even when the full authenticity of released datasets cannot be independently verified, the publication of partially credible material can still generate substantial reputational damage and potential operational disruption for affected organizations.
Targeting critical infrastructure has emerged as one of the most concerning aspects of the current cyber activity by pro-Iran hacktivists and proxy collectives. Groups operating in this ecosystem, including Iranian APTs, Handala, and networks associated with the Cyber Islamic Resistance umbrella, have publicly claimed operations targeting infrastructure across the region. Recent Telegram posts indicate that an Iranian APT group claimed responsibility for attempts to sabotage Jordanian critical infrastructure, while other Iran-aligned hacktivist personas have asserted access to sectors including fuel systems, water utilities, and other operational technology environments.
In a separate case, the Handala Hack Team has alleged that it compromised both Oil and gas companies in the United Arab Emirates and Israel, claiming to have exfiltrated more than 1.3 TB of sensitive data from oil and gas sector networks. These claims, which would represent a significant intrusion into Middle Eastern energy infrastructure if confirmed, have circulated primarily through hacktivist communication channels and social media reporting and have not been independently verified.
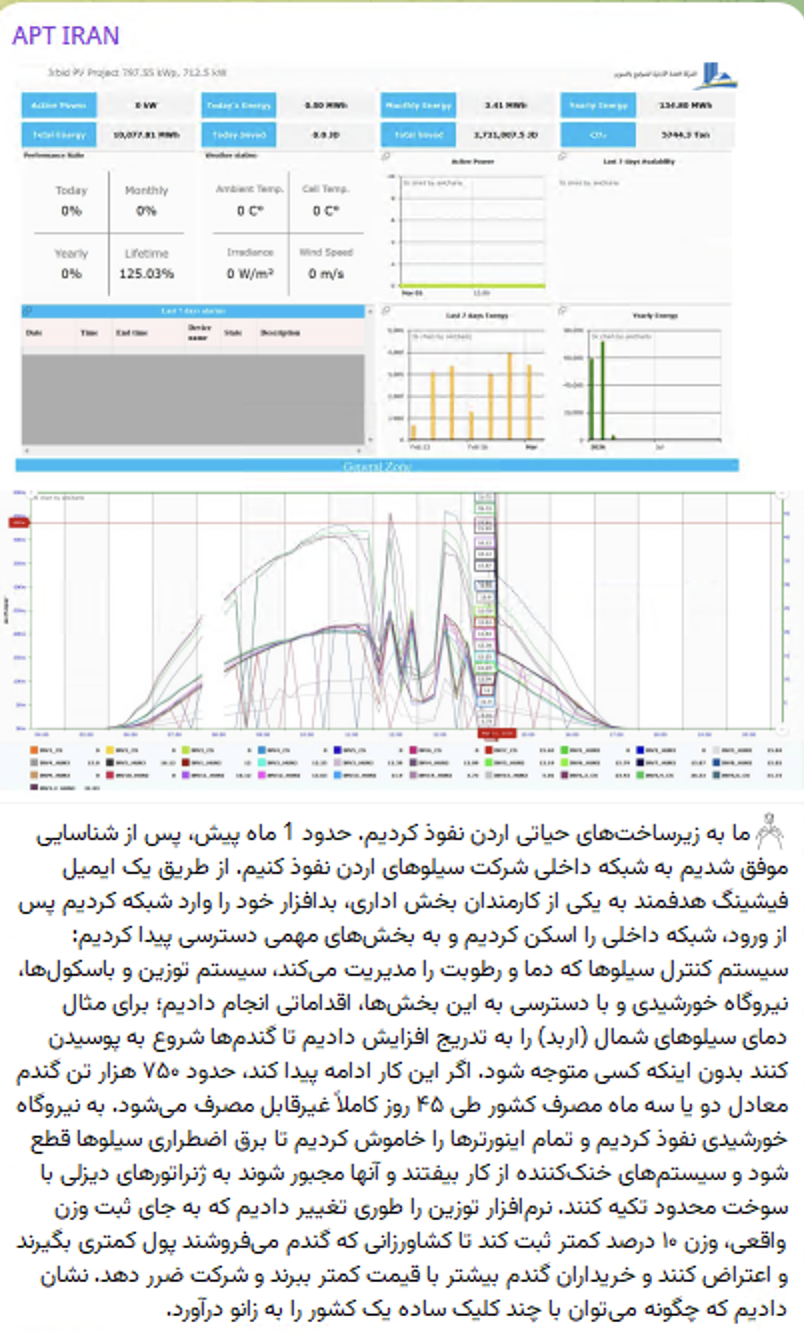
⠀
Although many of these claims remain difficult to independently verify, the recurring focus on industrial control systems and essential services is analytically significant. Hacktivist collectives aligned with Iranian geopolitical narratives frequently leverage infrastructure-related claims as part of information operations designed to amplify perceived impact, generate psychological pressure, and signal the potential for escalation into operational technology environments. Even when technical disruption is limited or exaggerated, the persistent narrative around infrastructure compromise can shape defensive priorities and highlight potential escalation pathways within the broader cyber conflict.
Sectoral exposure and risk landscape
In the current geopolitical context, cyberattacks extend far beyond military networks and defense institutions. Modern cyber operations increasingly aim to affect the broader ecosystem that supports government activity, economic stability, and public trust. Consequently, adversaries seek not only technically vulnerable targets but also organizations whose compromise or disruption can increase visibility, influence public perception, or create cascading effects across interconnected systems.
A successful intrusion into a widely used service provider, a major infrastructure operator, or a publicly accessible institution can quickly produce consequences that extend far beyond the initial target, affecting supply chains, service availability, and public confidence. In this context, cyber operations often serve multiple purposes simultaneously: intelligence gathering, strategic positioning within critical networks, and generating disruption or exerting influence during periods of heightened geopolitical tension.
At present, several sectors appear particularly exposed:
-
Government institutions and public administration
-
Defense and aerospace industry
-
Energy sector, including oil, gas, and electricity
-
Telecommunications providers
-
Financial services
-
Transportation systems
However, the risk landscape extends beyond these sectors themselves. Organizations that form part of the broader digital supply chain supporting these industries may also represent attractive entry points. This includes cloud service providers, managed service providers, technology vendors, and other third-party platforms that maintain privileged access to client environments. Compromising such intermediaries can allow adversaries to reach high-value targets indirectly. By gaining access to a supplier or service provider, attackers may obtain pathways into multiple networks simultaneously, access sensitive information, or move laterally across interconnected operational systems. Supply chain compromise, therefore, offers both scale and stealth, making it an increasingly common tactic in sophisticated cyber campaigns.
Geopolitical alignment can also influence targeting decisions. Organizations based in countries that host United States military assets or are publicly aligned with United States or Israeli policy positions may attract additional attention from adversaries. In these cases, targeting can carry symbolic, political, or strategic value beyond the immediate technical impact of the intrusion. Within this environment, cyber exposure can generally be understood through three overlapping targeting dynamics.
Symbolic targets include municipalities, universities, media outlets, and public institutions. These organizations may be targeted primarily for visibility, messaging, or propaganda purposes. Even limited disruption or data exposure can generate headlines and amplify the perceived reach of the attackers.
Operational targets include sectors that support everyday economic and social activity, such as telecommunications providers, transportation systems, payment networks, and fuel distribution infrastructure. Disruptions in these areas can quickly affect daily life, creating public anxiety and increasing pressure on authorities to respond.
Strategic targets consist of entities whose compromise offers long-term intelligence or operational value. This category includes defense contractors, major financial institutions, government networks, and operators of critical infrastructure. In these cases, adversaries may prioritize persistence and stealth to collect intelligence, monitor decision-making processes, or maintain access that could be leveraged during future crises.
Taken together, these targeting patterns illustrate a broader shift in cyber operations: Attackers are increasingly selecting targets not only for their intrinsic value, but for the broader political, economic, and societal effects that disruption or compromise can produce.
What should organizations monitor?
In the current phase of the conflict, organizations should continue to monitor for indicators that activity is shifting from opportunistic disruption toward deliberate intrusion or access preparation.
Internet-facing infrastructure is often the initial entry point. Elevated scanning or probing of public websites, VPN gateways, remote access portals, cloud services, and email authentication infrastructure may indicate early reconnaissance. While some scanning is routine, sudden increases in probing activity or authentication attempts should be treated as potential precursors to intrusion.
Phishing and social engineering campaigns are also likely to intensify. Threat actors may exploit developments in the conflict by using lures that reference civil defense alerts, battlefield updates, humanitarian messaging, or urgent requests that appear to originate from leadership or trusted partners. In some cases, malicious applications or replicas of legitimate services may be used to harvest credentials or deploy malware.
Credential misuse remains a primary access vector. Security teams should monitor for abnormal authentication patterns, including logins from unusual geographic locations, access at unexpected hours, repeated failed logins followed by success, changes to multi-factor authentication settings, or the creation of new privileged accounts.
Organizations operating critical infrastructure should closely monitor activities within their operational environments. Suspicious access to remote management platforms, unusual connectivity between IT and OT networks, or unexpected activity involving engineering workstations or vendor access channels may signal reconnaissance within sensitive systems.
Finally, monitoring the broader information environment can provide early warning and signal the need to increase monitoring. Hacktivist groups frequently use platforms such as Telegram and X to circulate target lists, claim attacks, or release fragments of allegedly stolen data tied to geopolitical events. Tracking these channels can help organizations identify potential targets and strengthen their defensive posture before malicious activity reaches their networks.
Additional reading from Rapid7 Labs, for Rapid7 customers: Rapid7 Detection Coverage for Iran-Linked Cyber Activity
Checking out the Supermicro NVIDIA B300 Solutions and What it Takes to Build an AI Factory
Post Syndicated from Patrick Kennedy original https://www.servethehome.com/checking-out-the-supermicro-nvidia-b300-solutions-and-what-it-takes-to-build-an-ai-factory/
We take you on a tour looking a the Supermicro NVIDIA B300 generation versus the NVIDIA B200 generation and the other components of an AI factory
The post Checking out the Supermicro NVIDIA B300 Solutions and What it Takes to Build an AI Factory appeared first on ServeTheHome.
Amazon Redshift DC2 migration approach with a customer case study
Post Syndicated from Satoru Ishikawa original https://aws.amazon.com/blogs/big-data/amazon-redshift-dc2-migration-approach-with-a-customer-case-study/
This is a guest post by Satoru Ishikawa, Solutions Architect at Classmethod in partnership with AWS.
In April 2025, AWS announced the deprecation of Amazon Redshift DC2 instances, guiding users to migrate to either Redshift RA3 instances or Redshift Serverless. Redshift RA3 instances and Serverless adopt a design that separates storage and compute, offers new features such as data sharing, concurrency scaling for writes, zero-ETL , and cluster relocation.
In this post, we share insights from one of our customers’ migration from DC2 to RA3 instances. The customer, a large enterprise in the retail industry, operated a 16-node dc2.8xlarge cluster for business intelligence (BI) and ETL workloads. Facing growing data volumes and disk capacity limitations, they successfully migrated to RA3 instances using a Blue-Green deployment approach, achieving improved ETL query performance and expanded storage capacity while maintaining cost efficiency.
Amazon Redshift architecture types
Amazon Redshift offers two deployment options: Provisioned mode, where you choose the instance type and number of nodes and manage resizing as needed, and Redshift Serverless, which automatically provisions data warehouse capacity and intelligently scales the underlying resources. The following diagram compares these two architecture types.

Provisioned clusters require you to determine cluster size in advance, but you can optimize costs by purchasing Reserved Instances (RI) or scheduling pause and resume actions. Serverless automatically provisions resources as needed, with a pay-per-use model where you only pay for compute resources consumed. Both services support migration between each other and offer the same features including SQL, zero-ETL, and Federated Query capabilities. For specific pricing details, see Amazon Redshift pricing.
Provisioned clusters are suitable for large-scale, predictable workloads and offer automatic scaling based on queuing. Serverless provides management-free automatic scaling for variable workloads with AI-driven optimization that scales based on workload complexity and data volumes. For more details, refer to Comparing Amazon Redshift Serverless to an Amazon Redshift provisioned data warehouse.
Customer case study: Migration from DC2 instances
This section describes the customer’s migration from Amazon Redshift DC2 to RA3 instance types. The migration used a Blue-Green deployment approach that minimized downtime while achieving both cost optimization and performance improvement.
The customer’s workload had the following characteristics:
Use cases
The customer had the following key use cases for their Amazon Redshift deployment:
- Query via BI tool during business hours
- High volume of read queries
- Peak access during Mondays and beginning of months
- Data processing in early morning
- Concentrated write queries for data loading and transformation
- Steady-state workload characteristics
- Run queries more than 16 hours daily
Requirements
The customer had the following key requirements for their Amazon Redshift migration:
- Performance
- Use auto-scaling (such as concurrency scaling) during peak access periods
- Data size
- Disk capacity expansion needed
- Cost Management
- Easy budget prediction and management
- Utilize discount services for long-term usage
- Compatibility
- Maintain compatibility with existing applications and BI tools
- Avoid endpoint changes
- Availability
- Maximum downtime of 8 hours acceptable during migration
- Network
- Do not modify the existing 2-Availability Zone (AZ) subnet configuration
- When to migrate
- To be conducted during low-load days and hours
- Planned downtime possible within 8 hours
Key considerations in system design, implementation, and operation included extended operation hours, ease of budget prediction and management, cost optimization through Reserved Instances (RI), and maintaining compatibility with existing systems (avoiding endpoint changes). The customer evaluated Amazon Redshift Serverless, which offered attractive features such as a pay-per-use model, automatic scaling capabilities, and the potential for better price performance for variable workloads. While both Redshift Serverless and provisioned clusters could effectively support their workload patterns, the customer chose the provisioned model with RA3 nodes, leveraging their years of operational experience with provisioned environments, existing RI strategy, and established capacity planning approach.
Features of RA3 instance type
Built on the AWS Nitro System, RA3 instances with managed storage adopt an architecture that separates computing and storage, allowing independent scaling and separate billing for each component. These instances use high-performance SSDs for hot data and Amazon S3 for cold data, providing ease of use, cost-effective storage, and fast query performance. For more details, refer to Amazon Redshift RA3 instances with managed storage.
Migration prerequisites
The customer had the following migration prerequisites in place:
- The customer used a Redshift cluster with 16 nodes of dc2.8xlarge configuration.
- The customer chose a Blue-Green deployment approach for migration, where they would restore from a snapshot to RA3 instance type, enabling quick rollback if necessary.
- The customer implemented cluster switching and rollback through endpoint switching using cluster identifier rotation.
- Additionally, to improve performance with high concurrency, they transitioned the transaction isolation level from SERIALIZABLE ISOLATION to SNAPSHOT ISOLATION.
Cluster migration methods
There were two migration options available: Elastic Resize and Classic Resize.
Amazon Redshift’s Classic Resize functionality had been enhanced, for resizing to RA3 instance types, significantly reducing the write-unavailable period. Based on PoC testing, after initiating the resize, the cluster’s status was modifying for 16 minutes before it became available. Based on these results, the customer proceeded with the Classic Resize approach.
Cluster sizing
Sizing involved determining the instance type and number of nodes for the migration target. Sizing points considered workload characteristics such as CPU-intensive (queries using high CPU), I/O-intensive (queries with high data read/write), or both.When migrating from DC2 instance types, additional nodes might be required depending on workload requirements. Nodes were added or removed based on the computing requirements for necessary query performance.
Comparing configurations with similar cluster costs in terms of instance size and count, for a dc2.8xlarge 16-node cluster, the recommended configuration was 8 nodes of ra3.16xlarge. The following was the cost comparison in the Tokyo Region:
- Recommended: dc2.8xlarge 16-node cluster => ra3.16xlarge * 8-node cluster
- $97.52/h (6.095/h * 16 nodes) => $122.776/h (15.347/h * 8 nodes)
- Cost-focused: dc2.8xlarge 16-node cluster => ra3.16xlarge * 6-node cluster
- $97.52/h (6.095/h * 16 nodes) => $92.082/h (15.347/h * 6 nodes)
For this migration, the customer proceeded with a cost-efficient 6-node ra3.16xlarge cluster to stay within existing budget constraints. However, since this node count could face throughput limitations during certain times, they enabled concurrent scaling for the RA3 instance type to handle spike access.
Concurrency scaling provides up to 1 hour of free credits per day for each active cluster, accumulating up to 30 hours. On-demand usage fees apply when exceeding this free tier.While the customer chose to implement concurrency scaling, Elastic Resize to temporarily increase nodes during peak loads was also considered but rejected due to on-demand costs for additional nodes and the brief disconnection period during switching.
Managed storage cost
RA3 instances use Redshift Managed Storage (RMS), which is charged at a fixed GB-month rate. The customer’s approximately 2 TB of data required including storage costs in the estimates. For pricing details, see Amazon Redshift pricing.
Migration step from DC2 to RA3
After creating an RA3 cluster from the DC2 cluster’s snapshot, the customer swapped the cluster identifiers. The following diagram shows this process.

- Take a snapshot of the current DC2 cluster.
- Restore RA3 cluster from the snapshot with a different cluster identifier (Classic Resize)
- Swap the cluster identifiers between the current DC2 cluster and the new RA3 cluster.
If any issues arise after the cluster switch, you can quickly roll back by returning the original DC2 cluster to its original cluster identifier.
Note: Restore from a snapshot
Running the restore operation using CLI commands is recommended to minimize operational errors and ensure reproducibility. The following is a sample command.
Production migration duration
The time required for the restore and classic resize steps can vary significantly depending on data volume and target cluster specifications. The customer conducted a rehearsal beforehand to measure the actual required time.
Test results
Before the production migration, the customer created a test cluster by restoring a snapshot to the RA3 instance type. While Redshift Test Drive is typically useful for workload testing, this customer faced unique constraints: enabling audit logging in their production cluster would require configuration changes, cluster restarts, and complex approval processes under their strict change management policies. To address this, they developed a custom load testing tool that captured workload patterns using Amazon Redshift system views (SYS_QUERY_HISTORY and SYS_QUERY_TEXT), which maintain 7 days of query history. The tool replayed 55,755 historical queries with 50-way parallelism against both DC2 and RA3 clusters, comparing metrics including query execution time, CPU utilization, and disk I/O. Query result caching was disabled during testing to ensure accurate comparisons.
BI query performance
BI queries were tested using the custom load testing tool. The results represent the average execution time from 15 test runs of 55,755 queries executed with 50-way parallelism. Without concurrency scaling, the dc2.8xlarge 16-node cluster averaged 45.82 seconds per query, while the ra3.16xlarge 6-node cluster averaged 91.30 seconds. This indicated that RA3 instances showed longer execution times for short and medium queries in a direct migration without optimizations. However, enabling concurrency scaling improved RA3 performance progressively. With concurrency scaling enabled at maximum 2 clusters, the ra3.16xlarge 6-node cluster achieved an average of 72.48 seconds per query, a 21% improvement over the non-scaled configuration.
| Node Type / Number of nodes | Average Query Time |
| ra3.16xlarge 6-node cluster | 72.48 seconds |
ETL query performance comparison
For long-running ETL queries (execution time greater than 10 minutes), the RA3 cluster demonstrated better performance than DC2. These results represented a direct migration of the customer’s workload with no optimizations applied.
- For the Large-scale data load workload 1, the ra3.16xlarge cluster completed the query 28% faster than the dc2.8xlarge cluster (41 minutes vs. 57 minutes).
- For the Complex transformation workload 1, the ra3.16xlarge cluster was 23% faster (1 hour 1 minute vs. 1 hour 20 minutes).
These results indicated that the RA3 node type was more performant for time-intensive data loading and transformation tasks. The higher CPU utilization values for RA3 suggested more effective compute resource usage.
| Node Type / Number of nodes | Average Query Time | MAXCPU% |
| ra3.16xlarge 6-node cluster | 41 mins 09 seconds | 11:45 |
| dc2.8xlarge 16-node cluster | 57 mins 07 seconds | 10:85 |
| Node Type / Number of nodes | Average Query Time | MAXCPU% |
| ra3.16xlarge 6-node cluster | 1 hour 01 mins 33 seconds | 74:23 |
| dc2.8xlarge 16-node cluster | 1 hour 20 mins 36 seconds | 53:58 |
Performance tuning
Based on the test results, the customer identified that RA3 showed longer execution times for short and medium BI queries but faster performance for long-running ETL queries compared to DC2. To optimize overall performance, they focused on identifying slow queries and frequently referenced tables, prioritizing optimizations with the highest impact.
Performance tuning strategy
The customer considered several optimization strategies to leverage RA3’s architectural advantages. One key strategy involved pre-processing ad-hoc short and medium query workloads during low-load periods, creating pre-processed tables or materialized views for queries that repeatedly performed joins, aggregations, filters, and projections. RA3’s separated compute and storage architecture, with cost-effective large-scale storage, supported this approach.
Converting regular views to materialized views
Analysis of slow queries revealed the use of joins in views, and frequently referenced tables were being accessed multiple times through these views. As a countermeasure, the customer replaced frequently used regular views with materialized views, removing unnecessary data ranges and redundant columns.
Amazon Redshift supports incremental updates of materialized view contents via the REFRESH MATERIALIZED VIEW command, enabling efficient data updates.
Materialized views and query rewrite
By converting regular views to materialized views, existing queries may be automatically optimized through the “query rewrite” feature provided by the query planner. For more details, refer to “Automatic query rewriting to use materialized views“.
Automatic tuning with AutoMV
On the DC2 cluster, disk utilization consistently exceeded 80%, which disabled the AutoMV feature due to insufficient disk space. With RA3’s expanded storage, automatic tuning through AutoMV became possible, leading to further performance improvements. For more details about AutoMV, refer to Automated materialized views.
Performance tuning results
After applying these optimizations, the customer achieved the following results:
- Maintained existing performance while controlling cost increases
- Achieved higher CPU utilization while maintaining throughput
- Enhanced dynamic throughput during peak load periods using concurrency scaling’s automatic scaling
Conclusion
In this post, you learned how a large retail enterprise successfully migrated from Amazon Redshift DC2 to RA3 instances. The Blue-Green deployment approach enabled a safe migration with quick rollback capability, while the separated compute and storage architecture of RA3 provided flexibility to handle growing data volumes. Although RA3 showed different performance characteristics for short BI queries compared to DC2, the customer achieved significant improvements in long-running ETL query performance (up to 28% faster for data loads and 23% faster for complex transformations). By leveraging RA3-specific features such as materialized views and AutoMV, they optimized overall query performance while maintaining cost efficiency through Reserved Instances and concurrency scaling.
To continue your RA3 migration journey, see Best practices for upgrading from Amazon Redshift DC2 to RA3 and Amazon Redshift Serverless and Resize Amazon Redshift from DC2 to RA3 with minimal or no downtime for additional guidance and best practices.
About the authors
Introducing Moonforge: a Yocto-based Linux OS (Igalia Blog)
Post Syndicated from jzb original https://lwn.net/Articles/1062451/
Igalia has announced
the Moonforge Linux
distribution, based on OpenEmbedded
and Yocto.
Moonforge is an operating system framework for Linux devices that
simplifies the process of building and maintaining custom operating
systems.It provides a curated collection of Yocto layers and configuration
files that help developers generate immutable, maintainable, and
easily updatable operating system images.The goal is to offer the best possible developer experience for
teams building embedded Linux products. Moonforge handles the complex
aspects of operating system creation, such as system integration,
security, updates, and infrastructure, so developers can focus on
building and deploying their applications or devices.
Soap Opera Cameos #lastweektonight
Post Syndicated from LastWeekTonight original https://www.youtube.com/shorts/jio-0yE5VJE
Can Democrats Actually Win in Texas? | The David Frum Show
Post Syndicated from The Atlantic original https://www.youtube.com/watch?v=6x0O7DgC3sA
[$] HTTPS certificates in the age of quantum computing
Post Syndicated from daroc original https://lwn.net/Articles/1060941/
There has been ongoing discussion in the
Internet Engineering Task Force (IETF)
about how to protect internet traffic against future quantum computers. So far,
that work has focused on key exchange as the most urgent problem; now,
a new IETF working group is looking at adopting post-quantum cryptography
for authentication and certificate transparency as well. The main challenge to
doing so is the increased size of
certificates — around 40 times larger. The techniques that the working group is investigating
to reduce that overhead could have efficiency benefits for traditional
certificates as well.
Security updates for Wednesday
Post Syndicated from jzb original https://lwn.net/Articles/1062403/
Security updates have been issued by AlmaLinux (kernel, kernel-rt, libvpx, nfs-utils, nginx:1.26, osbuild-composer, postgresql, postgresql:12, postgresql:13, postgresql:15, postgresql:16, and python-pyasn1), Debian (imagemagick), Fedora (perl-Crypt-SysRandom-XS and systemd), Mageia (yt-dlp), Oracle (delve, gimp, git-lfs, go-rpm-macros, image-builder, kernel, libpng, libvpx, mysql8.4, nfs-utils, osbuild-composer, postgresql16, postgresql:12, postgresql:13, postgresql:15, postgresql:16, python-pyasn1, python3, python3.12, python3.9, and thunderbird), SUSE (python-aiohttp, python-maturin, python311-pymongo, rclone, and util-linux), and Ubuntu (linux-nvidia, linux-nvidia, linux-nvidia-6.8, linux-nvidia-lowlatency, and python-geopandas).
Intel Intros Core Ultra 250K & 270K Plus Chips, Refreshing Desktop Arrow Lake for Enthusiasts
Post Syndicated from Ryan Smith original https://www.servethehome.com/intel-intros-core-ultra-250k-270k-plus-chips-refreshing-desktop-arrow-lake-for-enthusiasts/
With Intel’s latest-generation Panther Lake silicon (Core Ultra 3 series) being a mobile-only product generation, the task of carrying the torch for Intel’s desktop product lineup falls to the company’s existing Arrow Lake processors (Core Ultra 2 series) for a second year. A technologically solid but overall unexceptional processor lineup, Arrow Lake’s desktop existence has […]
The post Intel Intros Core Ultra 250K & 270K Plus Chips, Refreshing Desktop Arrow Lake for Enthusiasts appeared first on ServeTheHome.