Last month, I gave a talk at DEF CON on AI hacking: what happens when AIs become hackers. It’s a combination of the potentialities I raised in my 2022 book A Hacker’s Mind and the lessons we’re learning from current AI models engaging in hacking behavior. I’m really proud of the talk, and the fact that it gained over 100K views on YouTube in just a few days.
Also online is an interview with me in the AI Village.
A new Linux toolkit, identified by Rapid7 Labs, has been targeting organizations across South Korea’s automotive and media industries with minimal detection. The campaign made use of a HAProxy instance named “ted backdoor”, alongside trojanized versions of crond, agetty, atd, sshd, and polkitd. This previously undocumented framework enabled threat actors to execute remote commands on compromised servers, inject malicious scripts into web traffic, perform credential harvesting, and engage in long-term surveillance.
The standout feature of this toolkit is its depth of integration with the target environment. The ted backdoor is compiled as part of the victim’s existing HAProxy version 2.8.12. It uses its native filter API, internal memory pools, event scheduler, and process management infrastructure to intercept traffic and hide from monitoring, while genuine load balancing traffic operates as expected.
Operating alongside this are an SSH keylogger, a curl-based RAT, and a stager. The RAT maintains a watchdog thread dedicated to tracking HAProxy’s health, and reporting it back to the operator’s infrastructure. The earliest uploads on VirusTotal date back to mid-2025 and the involved HAProxy 2.8.12-0fdb194was released on 22 November 2024, establishing this as the earliest possible compilation date for this build.
The toolkit is attributed with medium confidence to DPRK APTs, given that the attacks Rapid7 observed were targeting South Korean media and automotive sectors, likely aiming at long-term espionage, the usage of simple xor-based encryption, custom substitution cipher, and the list of C2s hardcoded is associated to APT37 by ThreatFox and maltrail. Analysis shows that the ted backdoor could be part of a broader framework covering nginx backdoor as well. The ted plugin registers a custom HAProxy filter that hooks the HTTP parser to inspect and log high-value traffic, steal session cookies, and perform a client IP selection to decide whether to inject custom scripts in the webpage being rendered.
Technical analysis
Rapid7 researchers revealed that the toolkit was used in campaigns targeting South Korean automotive and media sectors likely dating back to early 2025. The number of trojanized binaries and functionalities found suggest the scope could be long-term cyber espionage and surveillance. However, gathered evidence does not suffice to establish a timeline nor how the initial access was performed.
At the time of analysis, both victims were running an edge webserver with ports 80, 443, and 25 exposed. Port 443 hosted the Groupware login portal and port 25 exposed a mail server. Either surface represents a plausible initial access vector consistent with documented Kimsuky tradecraft. Since the beginning of 2026 Kimsuky has been observed exploiting RCE vulnerabilities in externally accessible mail servers to compromise South Korean groupware vendors, while Groupware web portals represent the kind of exposed authenticated application that DPRK-nexus actors have repeatedly targeted for credential harvesting and exploitation. The specific entry point and any associated CVE remain unconfirmed pending further forensic evidence.
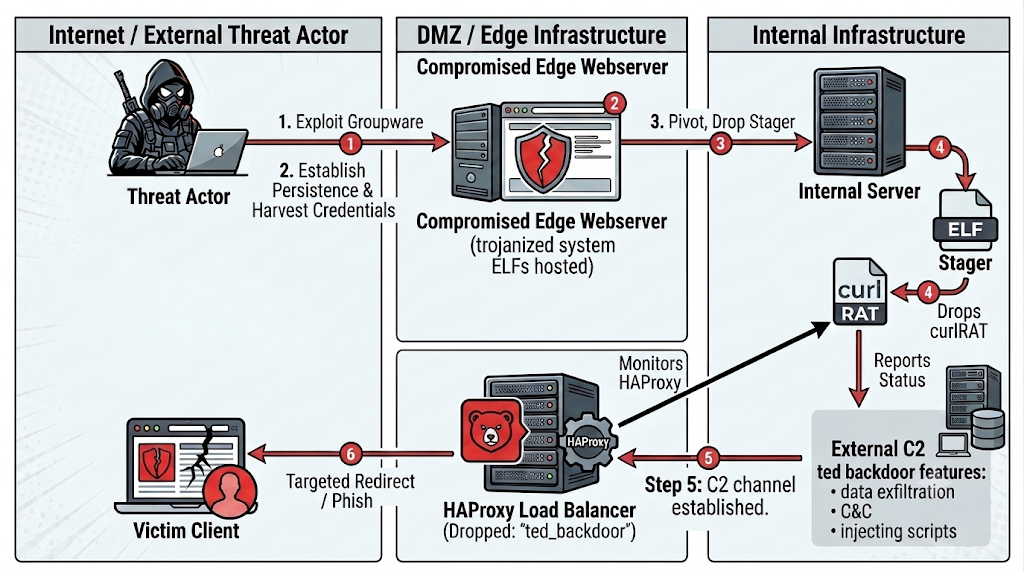
The scenario shown in Figure 1 assumes the initial access is obtained by exploitation of CVEs related to the Groupware portal.
Figure 1: Attack chain partially reconstructed
⠀
The threat actor begins by exploiting a vulnerability in the Groupware login portal running on the edge webserver, gaining an initial foothold in the DMZ. From there, they establish persistence and harvest credentials from the compromised edge host (e.g. SSH keylogger), which also doubles as a staging server hosting the trojanized system ELFs.
With a foothold on the edge, the attacker pivots inward and drops the stager onto internal servers. The stager checks for the presence of either crond or HAProxy, and only then deploys CurlRAT retrieving it either from its data section or the edge webserver.
In parallel, ted backdoor is dropped onto the HAProxy load balancer. Once active,it establishes its own C2 channel to the external operator infrastructure, enabling data exfiltration, command execution, and script injection. On the victim side, the compromised load balancer silently redirects or serves malicious content to selected clients browsing through it, completing the watering-hole loop.
SSH keylogger
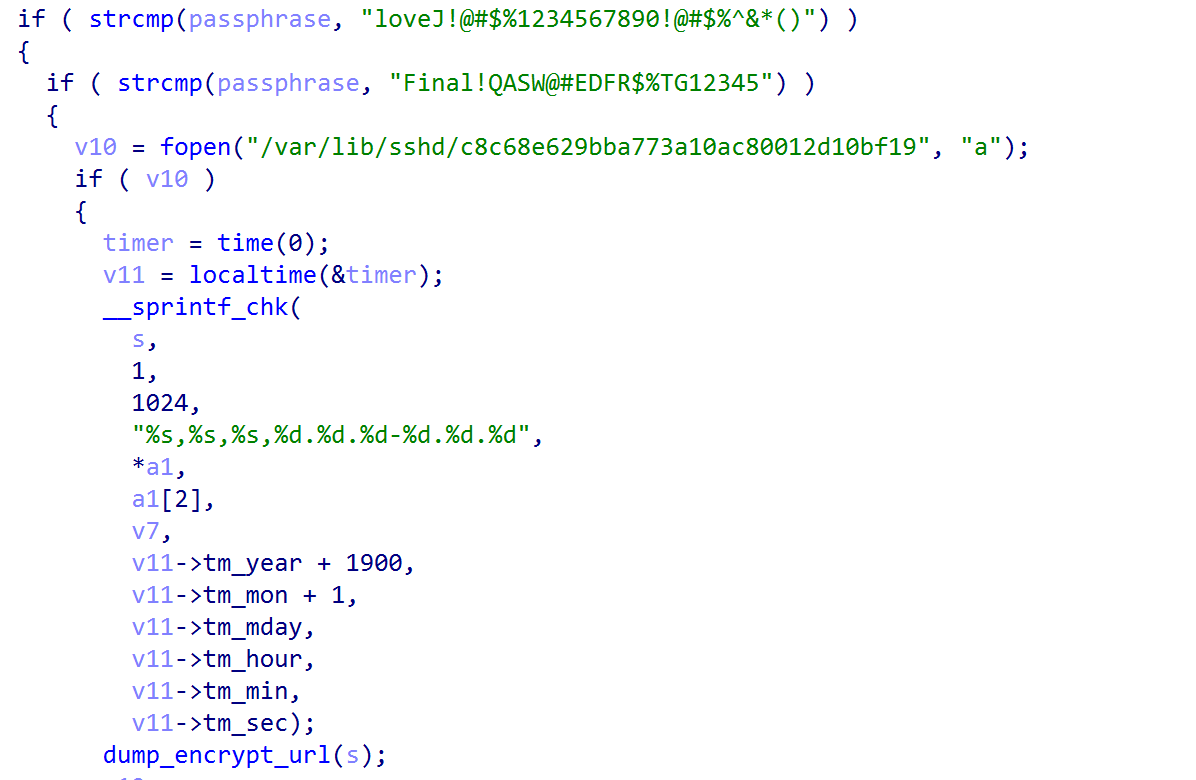
4bb923eb040aa13ca8fd409c31ee4729c60ddff32e350efe1c5a4a9168a065f5 intercepts legitimate users’ plaintext passwords and saves them to an encrypted log file under /var/lib/sshd/c8c68e629bba773a10ac80012d10bf19.
Figure 2: hardcoded master passwords in userauth_passwd()
⠀
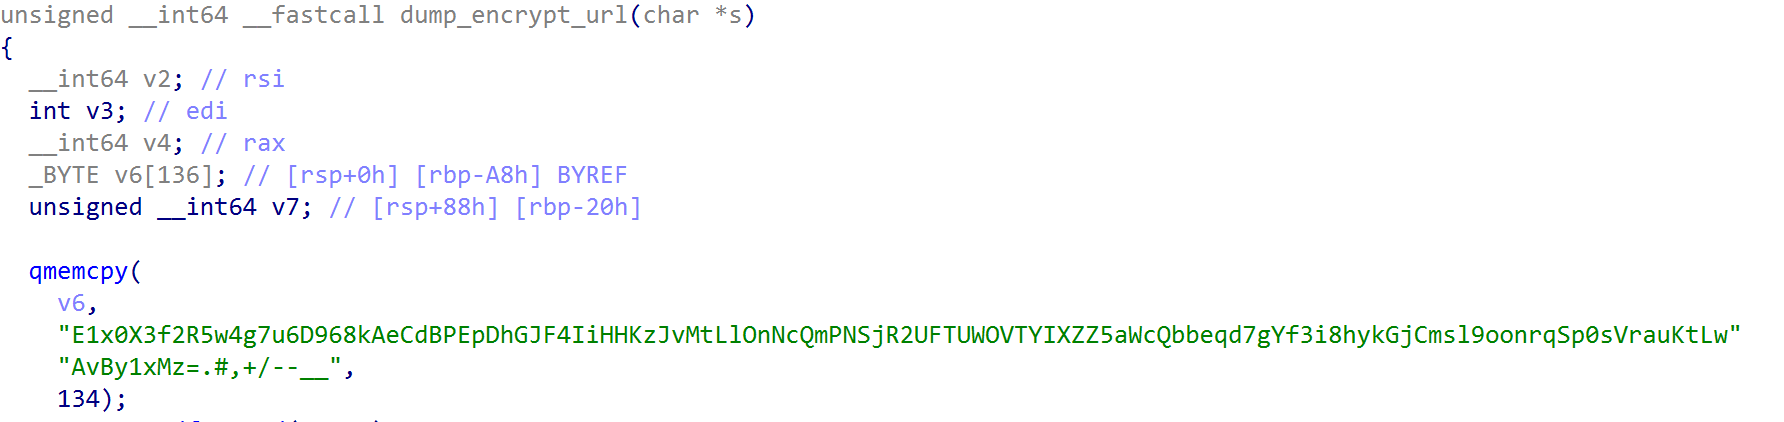
After checking that entered credentials are not equal to TA’s master passwords, userauth_passwd() proceeds to encrypt them using a custom substitution cipher recurring throughout the toolkit and base64 encoding.
Figure 3: Substitution cipher used to encrypt credentials
⠀
Pivoting from the above cipher, instances of polkitd, crond, agetty and atd binaries were identified using a similar encryption algorithm. Crond binaries were found to be delivered by a stager.
CurlRAT Stager
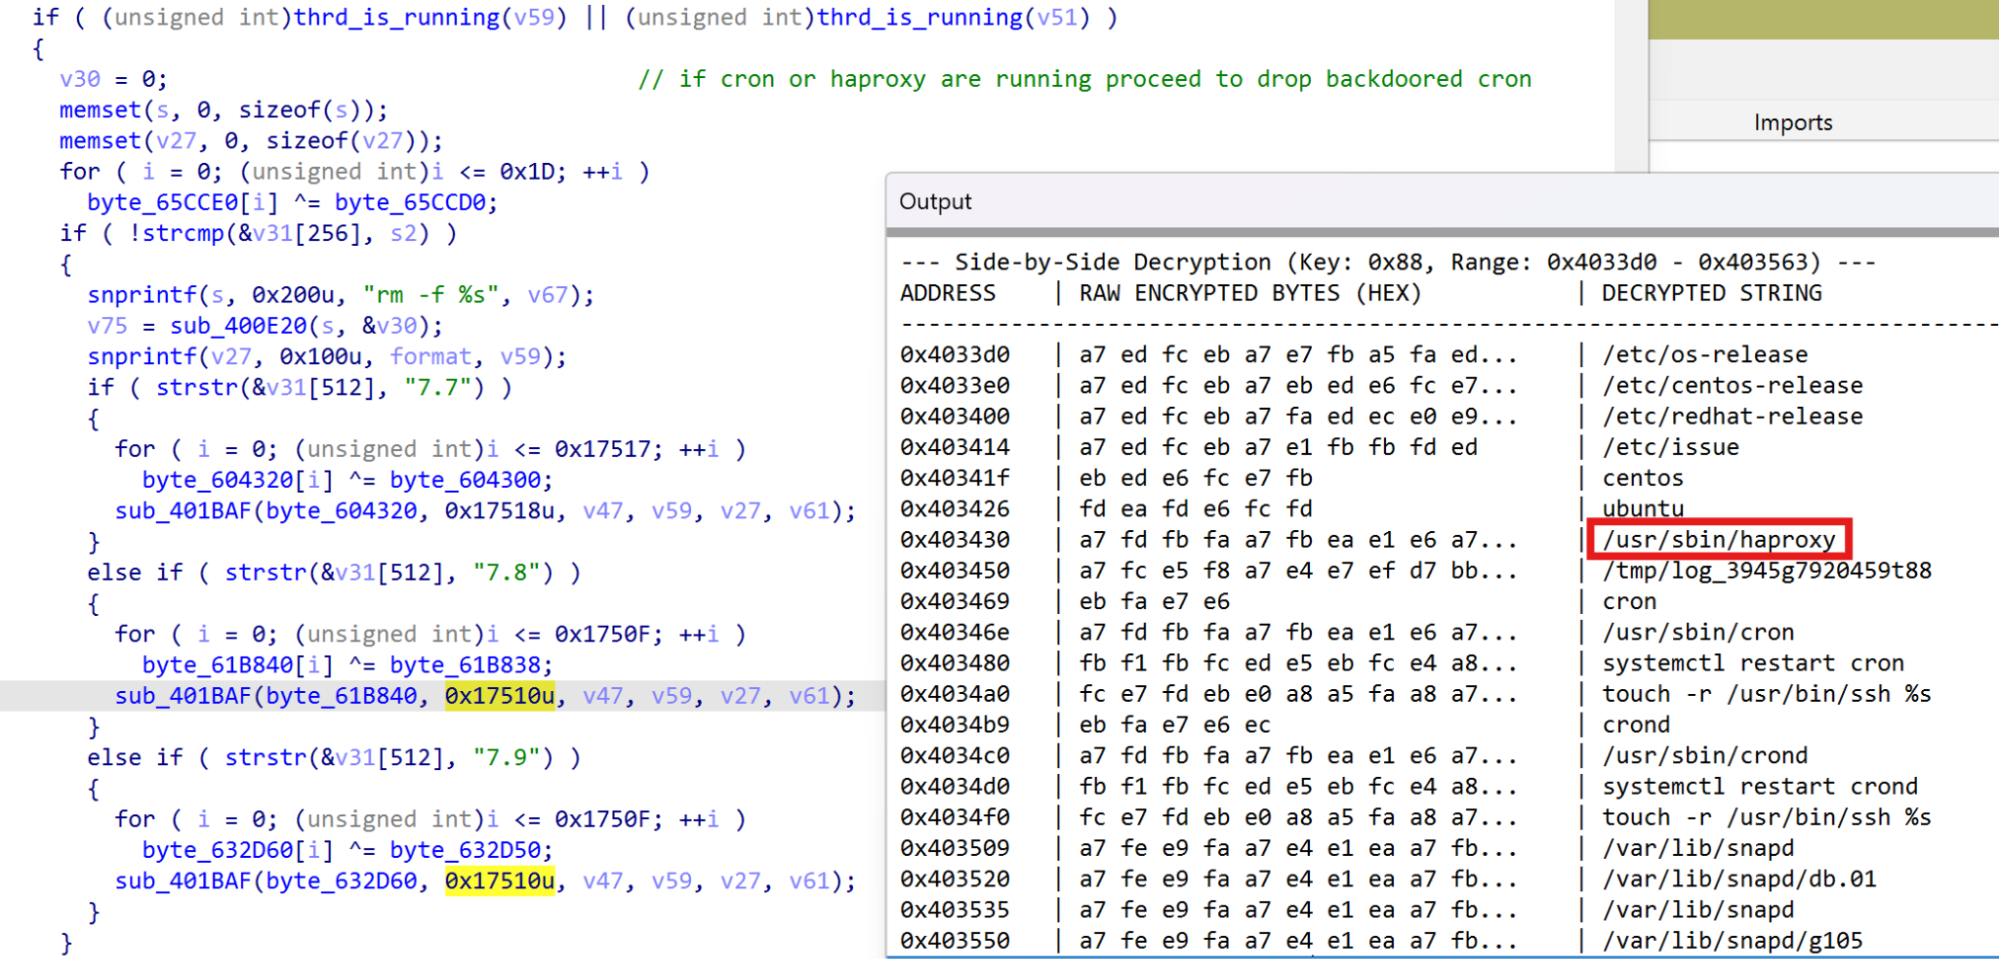
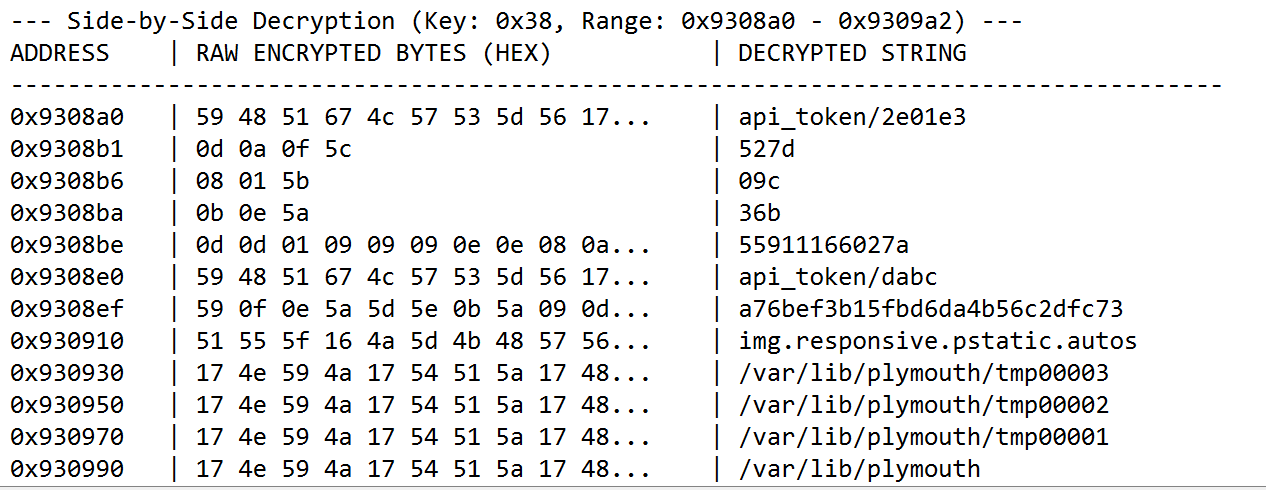
The stager 5db1b6d52faf60b4f32d6fd0c7c938e4d05d29a14c32ded4a9668357c08b6a91 starts by decrypting its configuration strings using a 1-byte XOR, then verifies root privileges and profiles the OS checking system hostname, OS distribution and version IDs, kernel release and version numbers and CPU architecture to select the correct payload to drop. It decrypts the trojanized crond binary in memory, overwrites the system’s legitimate daemon, and restarts the service. As shown below, only if HAProxy or cron are running on the system will it proceed to drop the backdoored crond.
Figure 4: Stager configuration
⠀
Checking for HAProxy presence is done as the binary, named by TA as ted backdoor. It also has RAT capabilities and plays a major role in the campaigns described. The embedded crond versions supported are CentOS 7.7, 7.8, 7.9 and Ubuntu 22.04 and after installing the backdoor, timestomping ensures the crond binary gets the same creation timestamp of /usr/bin/ssh. The stager ends by filtering out keywords such as tmp, wget cron and crond from Linux system logs using a staging file named /tmp/jasper-log, likely to blend in as the JSP (JavaServer Pages) engine in old Apache Tomcat versions, erasing any traces of the installation. The logs affected by the selective erasure are /root/.bash_history and the following under /var/log: messages, audit/audit.log, cmd.log, secure, syslog, auth.log.
09739441ed4599bac2f8159028f772f71e4b25c8badfff95574e56d7384f3dbe and fea1bc36632c71e5a839803469ef60ac47595d36b2c50934ac109ade6df06e61 are a different variant of the stager that fetches backdoored binaries from a compromised victim’s server without embedding any payloads.
CurlRAT
The Ubuntu version is analyzed below, though CentOS samples follow the same logic except for the filepath used to hide config/staging files.
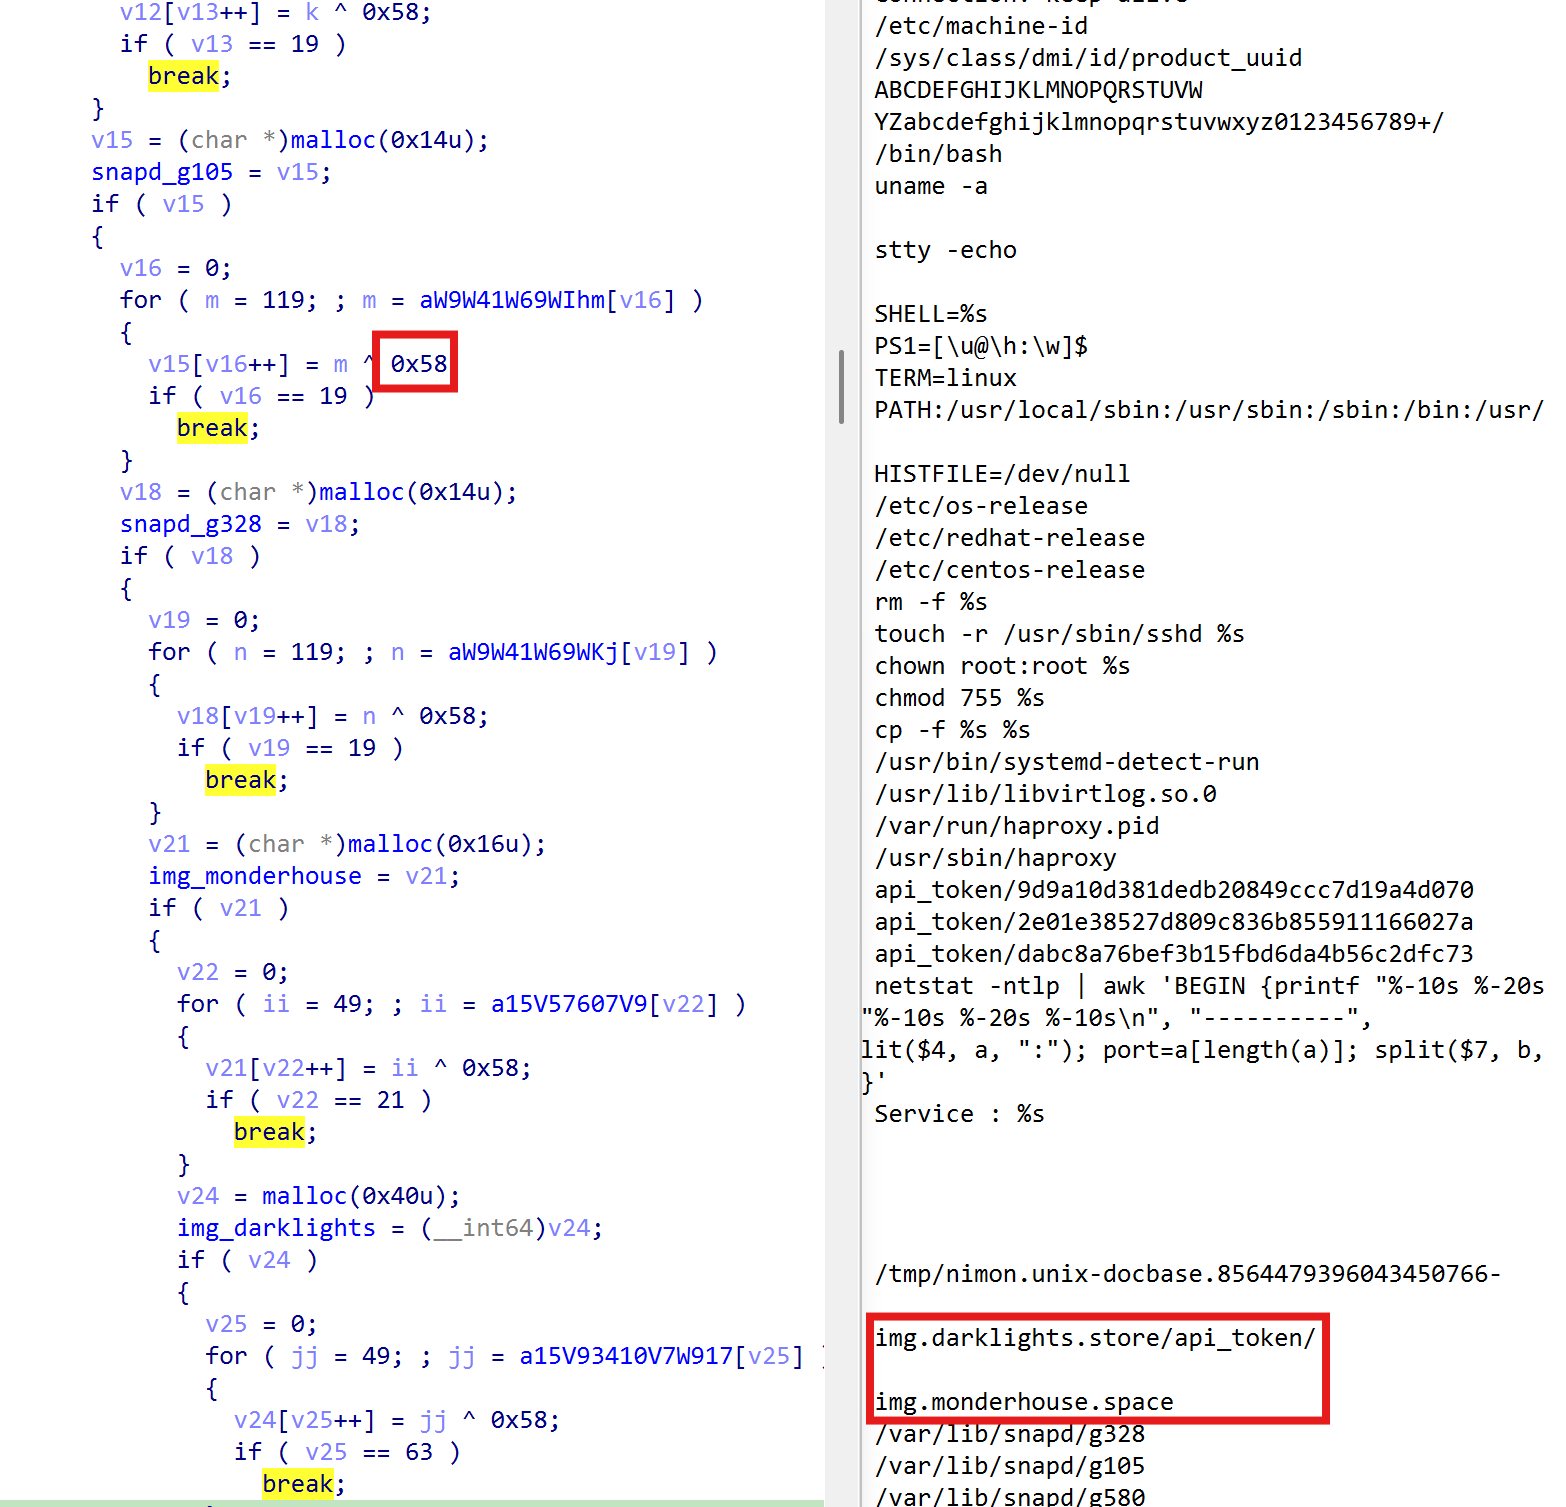
As for the stager, feeea9d0bf6ae7396d28271baa51ae50df5169ce5d32a516865856f91abc50b3 starts by decrypting configuration strings using a 1-byte XOR key (0x58).
Figure 5: curlRAT configuration
⠀
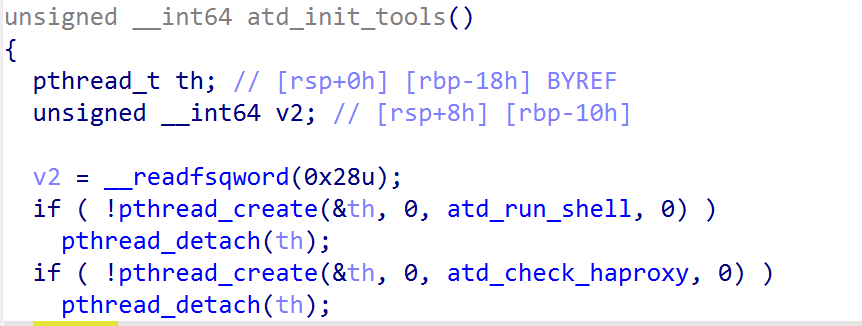
The main logic added to crond is executed via two threads. The first thread runs the start_routine function that creates the staging directory snapd under /var/lib, where it attempts to load the victim ID from /var/lib/snapd/g580. If network failures were previously recorded, it reaches out to a secondary domain – img.darklights.store – authenticating with api_token/ecd427ea8330a4ff73618483e00b9b41 and setting the User-token header to the victim ID to fetch updated configuration under /tmp/nimon.unix-docbase.8564479396043450766-db6fb4443bc, where it’s then copied into /var/lib/snapd/g105.
To decrypt the configuration, the first byte of the file initializes the seed of a feedback xor based cipher. Each poll cycle, a config file is fetched from the C2 server over HTTPS (falling back to HTTP on failure) using libcurl, with the victim token embedded in the User-token header. The fetched config is parsed for three single-character delimiters — ! terminates the credential field, # marks the payload section, and * separates arguments — after which the credential field is compared against the local victim token.
If authentication succeeds, a single-character mode byte (ASCII ‘0’ through ‘5’) preceding the delimiter “#” selects one of six handler routines via a jump table. Payloads embedded in the config are decoded through a two-stage pipeline: standard Base64 decoding followed by a rolling cumulative XOR cipher keyed from the decoded header. The C2 task handler sleeps for 43,200 seconds (12 hours) between polls by default, but the operator can activate a fast-poll mode by setting a flag, reducing the interval to 30 seconds. A retry loop calls the handler up to six times per cycle with five-second intervals, failing fast if the first attempt does not succeed. The table below shows the C2 commands accepted.
Mode
Function
Description
0
cmd execution
Base64 + XOR-decodes a command list from the config, executes each line via popen with stderr redirected to stdout, saves output into a 1 MB buffer, and sends the result back.
1
config write
Decodes and writes a new config payload to disk, validates it, and sets the polling interval and fast-poll flag. If the validation fails, the C2 resets to img.monderhouse.space
2
staged payload drop
Issues an authenticated HTTP POST to the C2 host with a task path as the body, streams the response to a temporary file, decompresses and moves it to the final drop path, unlinking the temp.
3
reverse shell
Closes all file descriptors above 2, calls setuid(0) and setreuid(0, 0), forcing both its real and effective user IDs to root, and connects out before handing off to the shell dispatcher.
4
beacon
Populates a 10 KB system-info structure and transmits it as a check-in beacon.
5
PTY shell
A full interactive PTY shell, the payload consists of an ip:port.
Modes 0–2 and 4 use libcurl-based HTTP/HTTPS, hence the name curlRAT. All modes use Base64+XOR encoding/decoding applied to the payload. The victim ID is obtained by concatenating “cron_3.0pl1-137ubuntu3“, system hostname, ipv4 address, and the hardware/OS UUID (read from /sys/class/dmi/id/product_uuid), then applying MD5 hash and converting it to uppercase.
The layer of encryption used for all C2 interactions consists of a feedback xor cipher using an initial random seed (modulo 240 + 10, 0<=seed<=249) and then applying Base64 encoding. The malware encapsulates the encrypted and encoded payload, the service name, and the telemetry type into a formatted application/x-www-form-urlencoded HTTP POST body (name=%s&value=%s&type=%d) which is sent to the C2 and authenticated using an hardcoded API token, including the victim ID in the User-token header.
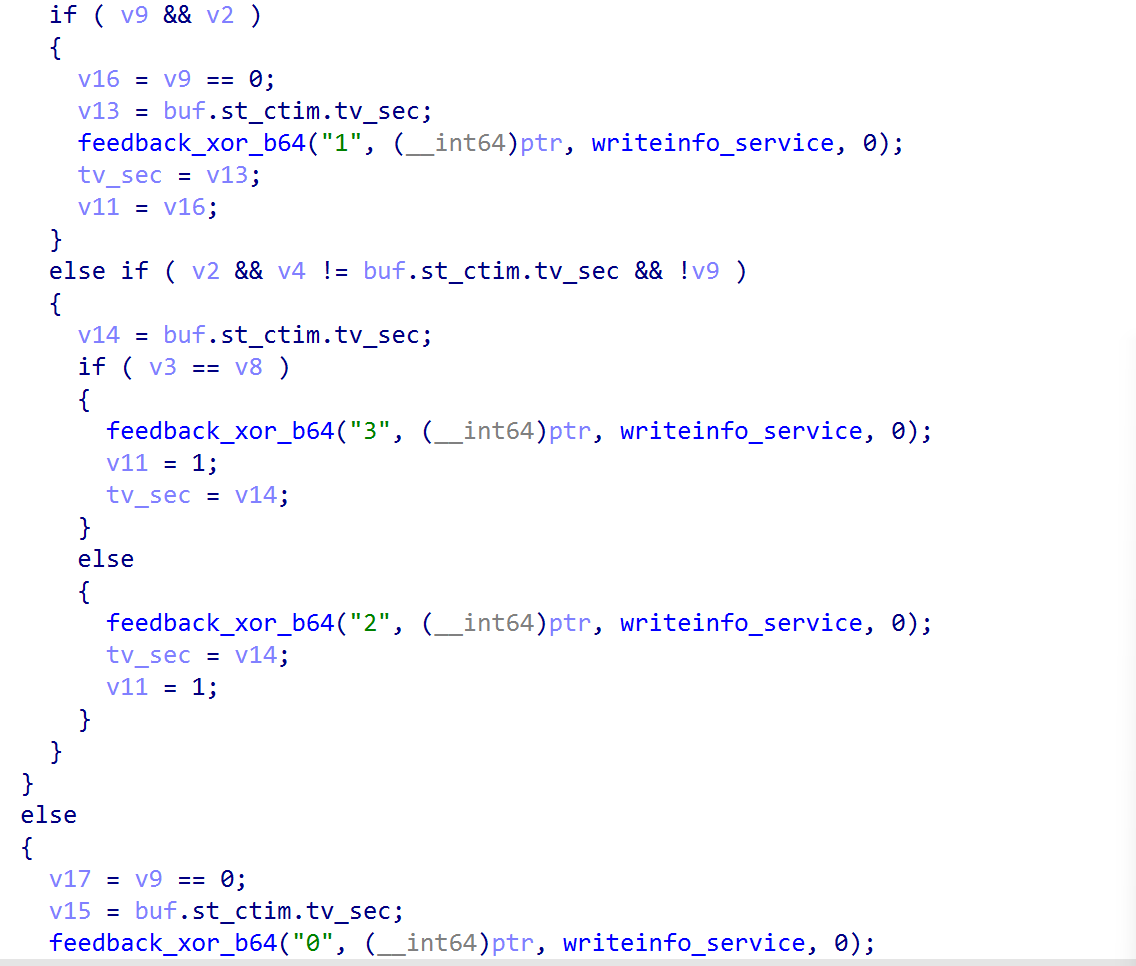
The second thread acts as the HAProxy watchdog. Before entering the monitoring loop, it checks for the presence of the file /usr/lib/libvirtlog.so.0 to ensure the target is running in a virtualized environment, otherwise it sleeps 6 minutes and aborts. Then it accesses the MD5 victim ID under /var/lib/snapd/g580 to check if the node is active and compromised. Every hour the watchdog reads the pid at /var/run/haproxy.pid and monitors the status of HAProxy by polling /proc/pid. The status can be one of the following codes:
0 (Started): Process transitioned from stopped to running
1 (Stopped): Process is no longer active in the kernel process table
2 (Restarted): PID file timestamp modified, and a new PID is detected
3 (Reloaded): PID file timestamp modified, but the PID remained identical
The status is then sent to the C2 endpoint “writeservice_info” using the custom crypto layer and the telemetry type set to 0 (Figure 6).
Figure 6: writeinfo_service monitoring HAProxy status
⠀
The CentOS versions of curlRAT contain the same functionalities, except that functions are masqueraded as atd_ routines to blend in during static analysis.
Figure 7: The two threads running curlRAT logic
⠀
Below is the table summarizing the main RAT components.
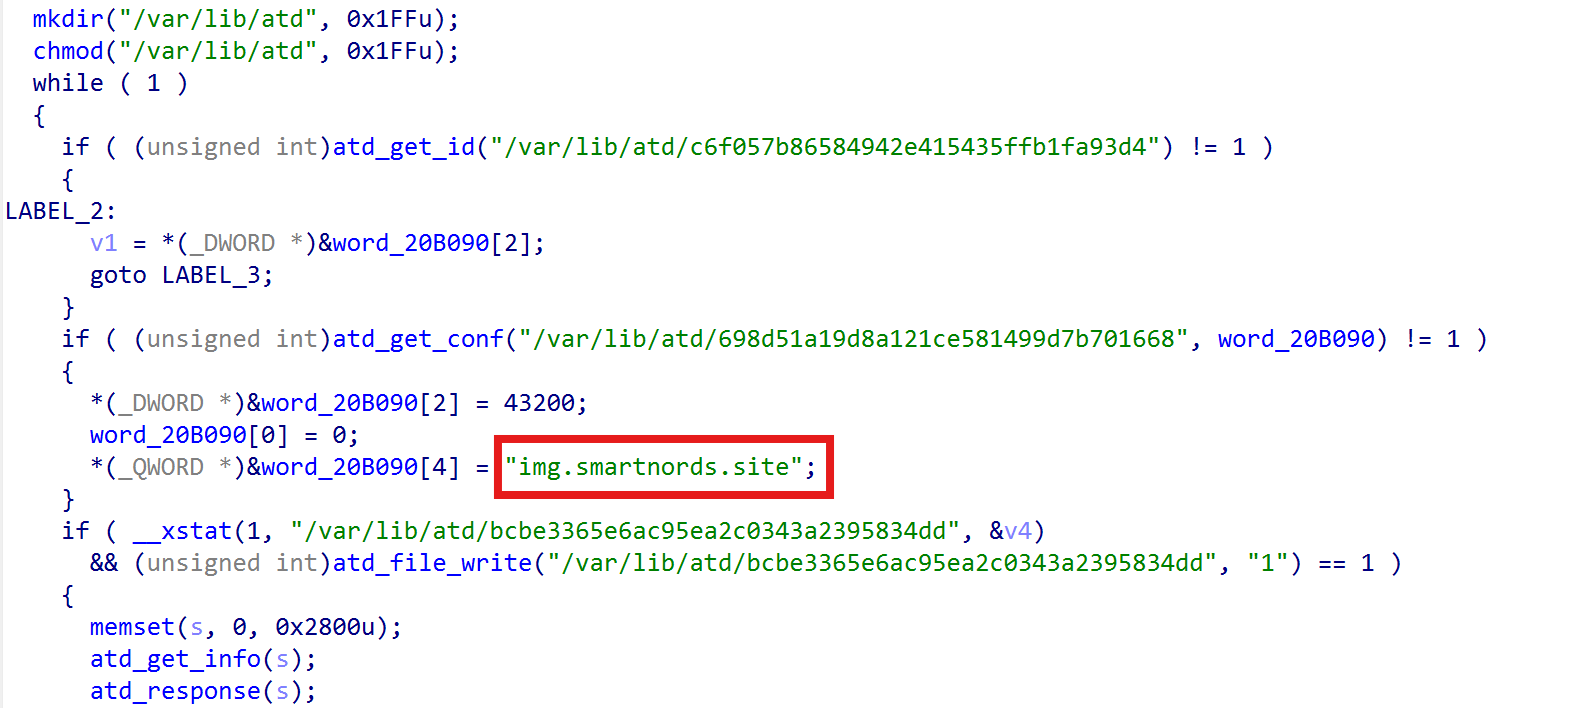
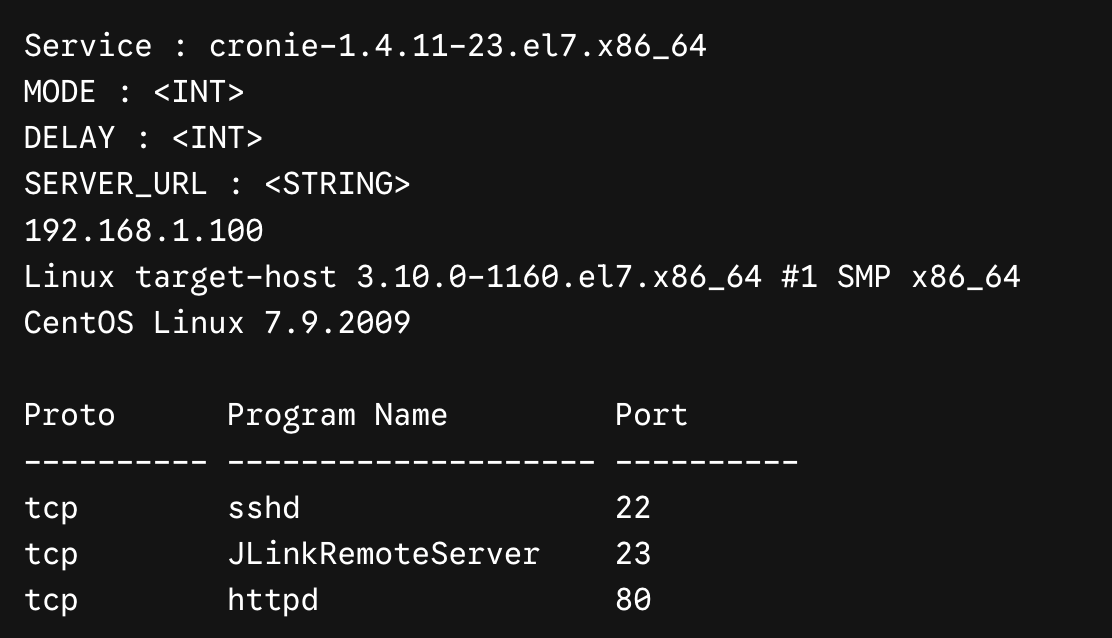
The atd_get_info() is a recon routine likely used to decide which binary trojanized next to ensure persistence on the node. It collects the service name of the compromised machine and sends it to the C2 via the atd_response routine together with Ipv4 address, OS version, and the list of services and listening port (Figure 9).
Figure 9: Recon module output sent to the C2
⠀
MODE, DELAY and SERVER_URL are parsed from the config file discussed previously. During the campaign observed by Rapid7, the RAT acts as a framework and constitutes the codebase to edit legitimate system daemons. Other trojanized instances found are agetty and polkitd, where we identified a similar pattern lacking the HAProxy monitor: the creation of a thread to run curlRAT, reaching to img.worksongo.store and img.socialteams.store respectively.
atd_encrypt_url and atd_decrypt_url leverages the substitution cipher “E1x0X3f2R5w4g7u6D968kAeCdBPEpDhGJF4IiHHKzJvMtLlOnNcQmPNSjR2UFTUWOVTYIXZZ5aWcQbbeqd7gYf3i8hykGjCmsl9oonrqSp0sVrauKtLwAvBy1xMz=.#,+/–__” shared with the ssh keylogger.
Ted backdoor
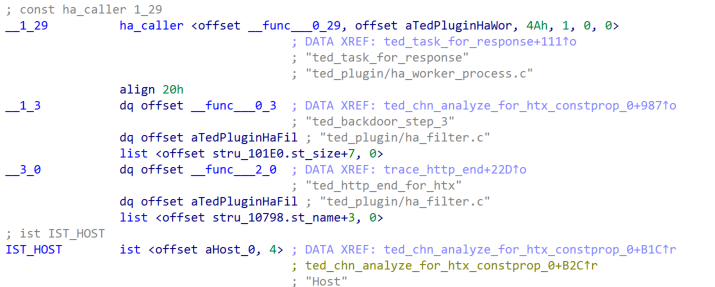
The TA recompiled the HAProxy build 2.8.12 72e70936f0dbe459142a1d867617c35f8d0cce5d18c6a49e1090a2a5adc8e558 (18MB) to include a custom plugin (named ted_plugin) leaving debug strings naming the backdoor.
Figure 10: ted_plugin compiled as part of the source code
⠀
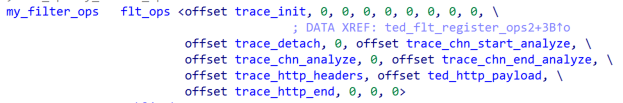
Figure 10 shows that the plugin was directly compiled with the rest of HAProxy source code and hooks directly the built-in HTTP parser relying on internal HAProxy structure for searching HTTP request headers.The custom filter defined to capture traffic is loaded via the ted_load_filter_config routine.
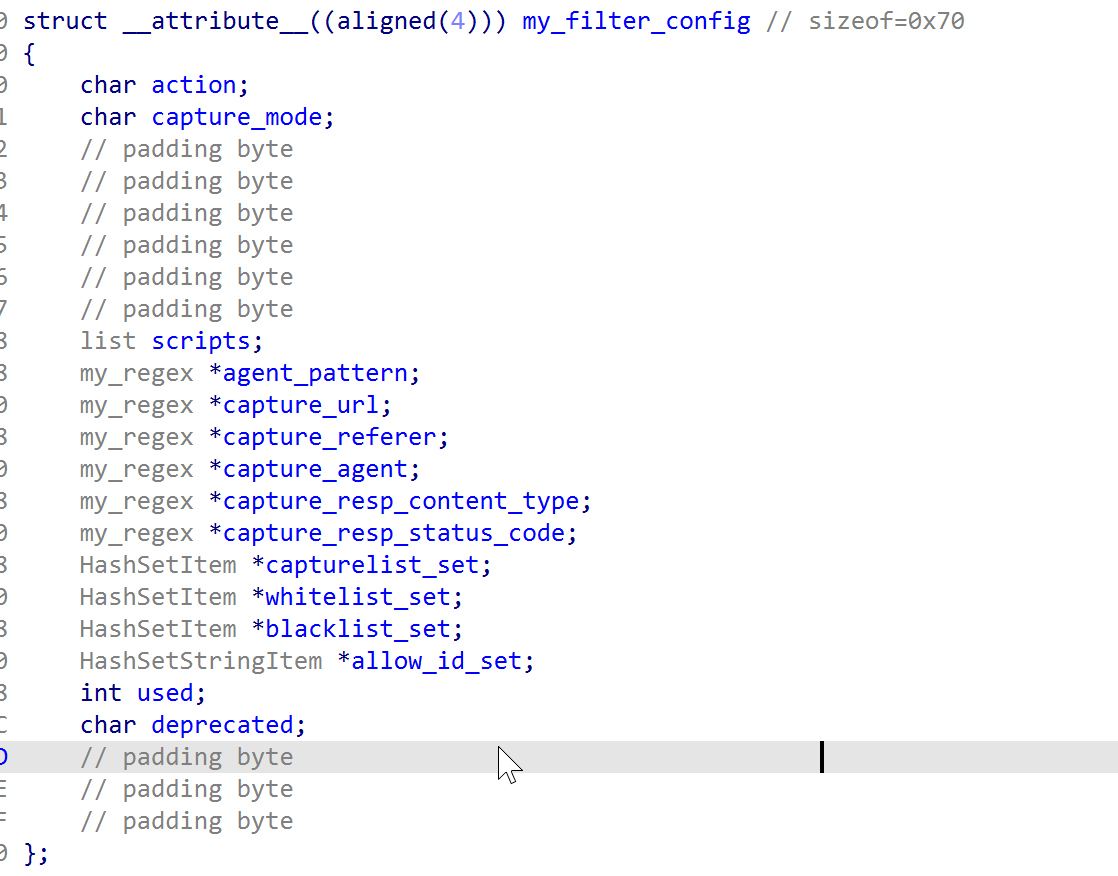
Figure 11: my_filter_config struct
⠀
The routine reads the implant’s operational configuration from ~/cache/haproxy-1000.cache. Each field is decrypted in two layers: first ngx_decode applies a chained XOR seeded by the file’s first byte; then ngx_decrypt_script applies a monoalphabetic substitution whose 67-entry mapping table is built at startup in ted_init_util from “E1x0X3f2R5w4g7u6D968kAeCdBPEpDhGJF4IiHHKzJvMtLlOnNcQmPNSjR2UFTUWOVTYIXZZ5aWcQbbeqd7gYf3i8hykGjCmsl9oonrqSp0sVrauKtLwAvBy1xMz=.#,+/–__” , and held in the ted_dec_dict uthash table keyed by Jenkins hash for O(1) lookup. The config carries the operating mode, all targeting regexes, every script rule with its payload paths and filenames, and the allowed operator keys. IP-based access control lists are loaded from haproxy-1001.cache and haproxy-1002.cache via the same decryption scheme. In other ted backdoor samples, the my_filter_config struct includes regexes to capture cookies as well.
After loading its configuration, it sets up signal handling via ted_register_reload_signal_handler() and saves its C2 pipe under HAPROXY_MWORKER_PP_READ and HAPROXY_MWORKER_PP_WRITE environmental variables to survive reloads and restarts, saving child process activity via ted_extra_log().
Below is the list of functions defined by the ted_plugin:
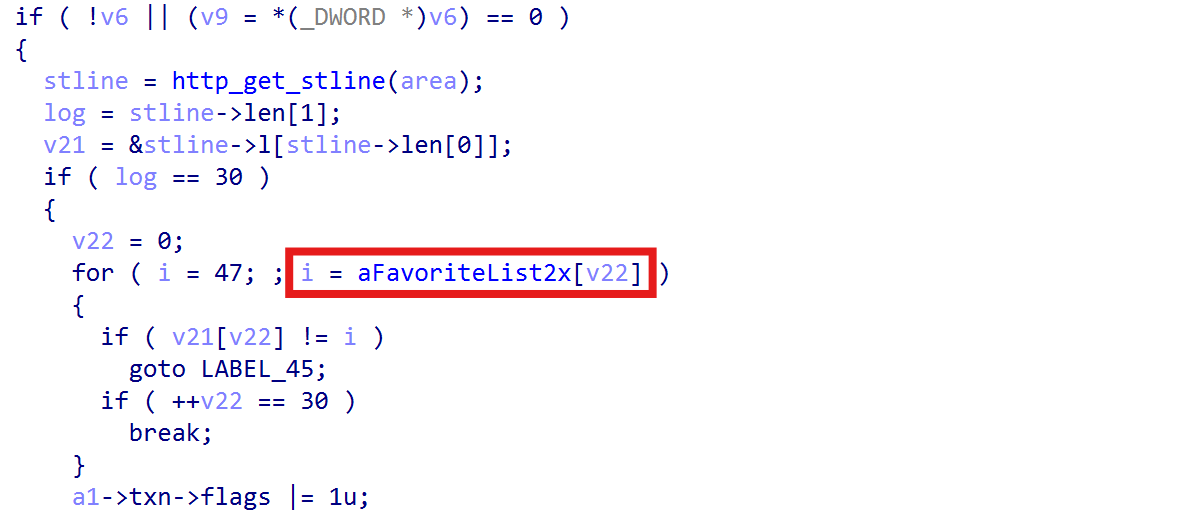
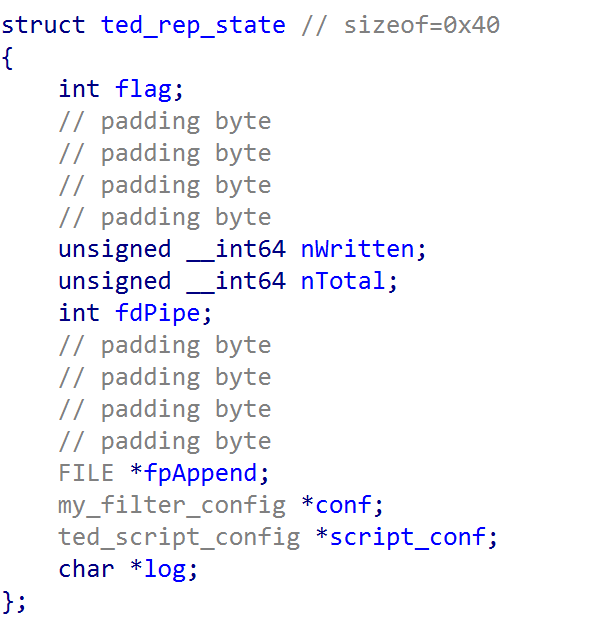
trace_chn_start_analyze() is hooked via ted_chn_analyze_for_htx_constprop_0() that parses the HTX buffer — the memory region where HAProxy stores parsed, SSL-decrypted HTTP request. If an incoming request matches the endpoint “/favorite_list_2x_m500_ico.jpg” (Figure 13), the malware drops into a Command & Control mode, setting the field flag to 1 in the ted_rep_state structure that tracks the response state.
⠀
Figure 13: Dropping into C2 mode
⠀
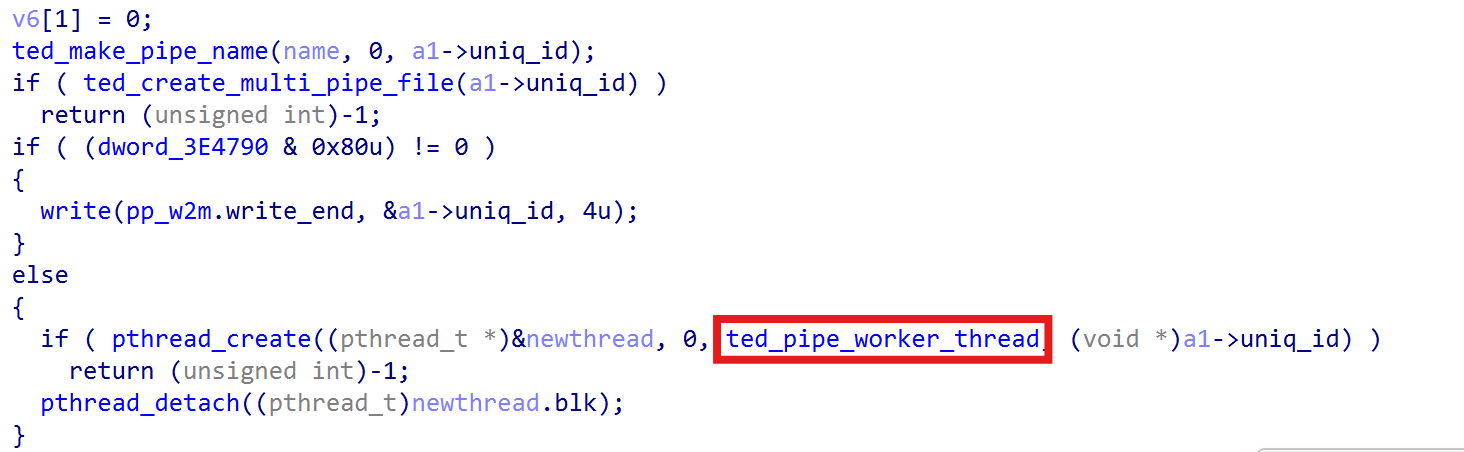
First, it reaches into HAProxy’s internal counters to decrement active connection stats, referencing fields from the proxy struct via hardcoded 2.8.12 offsets to clear any trace left: the per-backend beconn/feconn and the global actconn, then 64-bit fields within be_counters (cum_conn, cum_req, bytes_in, bytes_out) guarded against underflow, and 32-bit peak metrics (sps_max, conn_max, cps_max) decremented only when exactly 1. Secondly, it parses a custom hardcoded 14-byte header to obtain the payload length, then creates FIFO pipes via ted_make_pipe_name and ted_create_multi_pipe_file keyed on HAProxy’s connection ID under /tmp (e.g. /tmp/t[ID]_w.pipe). If HAProxy is running in master-worker mode (MODE_MWORKER, bit 0x80), the connection ID is written to the pp_w2m pipe so the master process runs the dispatcher; otherwise a detached thread runs ted_pipe_worker_thread locally (Figure 13).
The HTX walk filters on block type 4, which is HTX_BLK_DATA, and writes each block straight into fdPipe with write(). Any short write aborts and closes the pipe. Afterwards to_forward, output, buf.head and buf.data on the request channel are all zeroed. That tells HAProxy there is nothing left to forward, so the attacker’s command body never reaches a backend server. The C2 request terminates at the load balancer, and no backend ever logs it.
The C2 dispatcher logic is resumed in the table below.
Command
Description
Opcode ‘0’ (0x30)
Beacon: returns a version banner including build ID (24112201), HAProxy version (2.8.12-0fdb194), master-worker mode status, and chroot path.
Opcode ‘1’ (0x31)
File upload: resolves path via ted_build_correct_path, writes file content via fopen(path, “wb”), and replies 1. Used to upload payload files for the injection path.
Opcode ‘2’ (0x32)
File download: reads a path, stats it, writes the 8-byte size, and streams the contents back with EAGAIN handling.
Opcode ‘3’ (0x33)
Command execution: executes commands via popen; merges stdout/stderr, appends ” 2>&1″, and streams output back XOR-encrypted.
Opcode ‘9’ (0x39)
Config update: writes new config to ~/cache/haproxy-1000.cache.bak, re-encrypts using chained XOR, validates via ted_load_filter_config, and renames over the active config file if successful.
All five handlers write the same “HTTP/1.0 200 OK” header with Content-Type: text/html into the read pipe before the body. That’s what the response task then relays out via send() on the raw socket, which is why the traffic looks like an ordinary HTTP response on the wire despite never passing through HAProxy’s response path. Output back to the operator uses a rolling XOR cipher where each plaintext block is the key used to encrypt the next block with a random 1-byte seed.
If the initial endpoint check does not match “/favorite_list_2x_m500_ico.jpg” and the filter is in capture mode, then traffic is selectively logged and victims are identified based on the capturelist_set field within the my_filter_config struct (Figure 11), containing the list of targeted IPs and subnets. It uses regular expressions to filter the incoming HTTP traffic, waiting for high-value requests (like a user hitting a /login endpoint or an admin panel).
When a victim’s request matches the attacker’s filters, the backdoor goes to work.
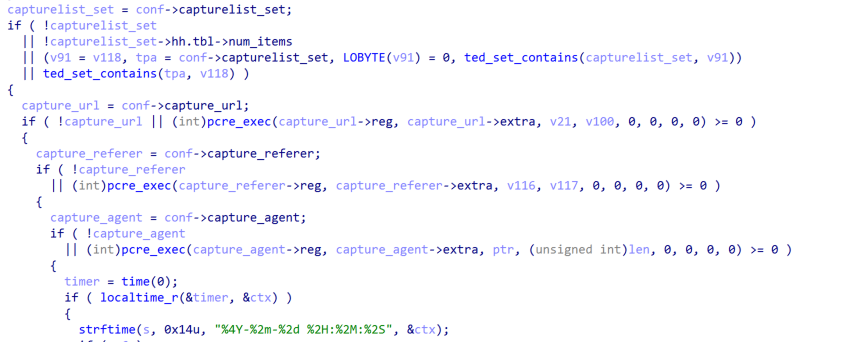
It extracts the victim’s source IP, the requested Host, the Referer, and the User-Agent formatting the data in a single-line record using exclamation marks as separators.
Figure 14: Real-time capturing of selected HTTP headers matching specific regexes
⠀
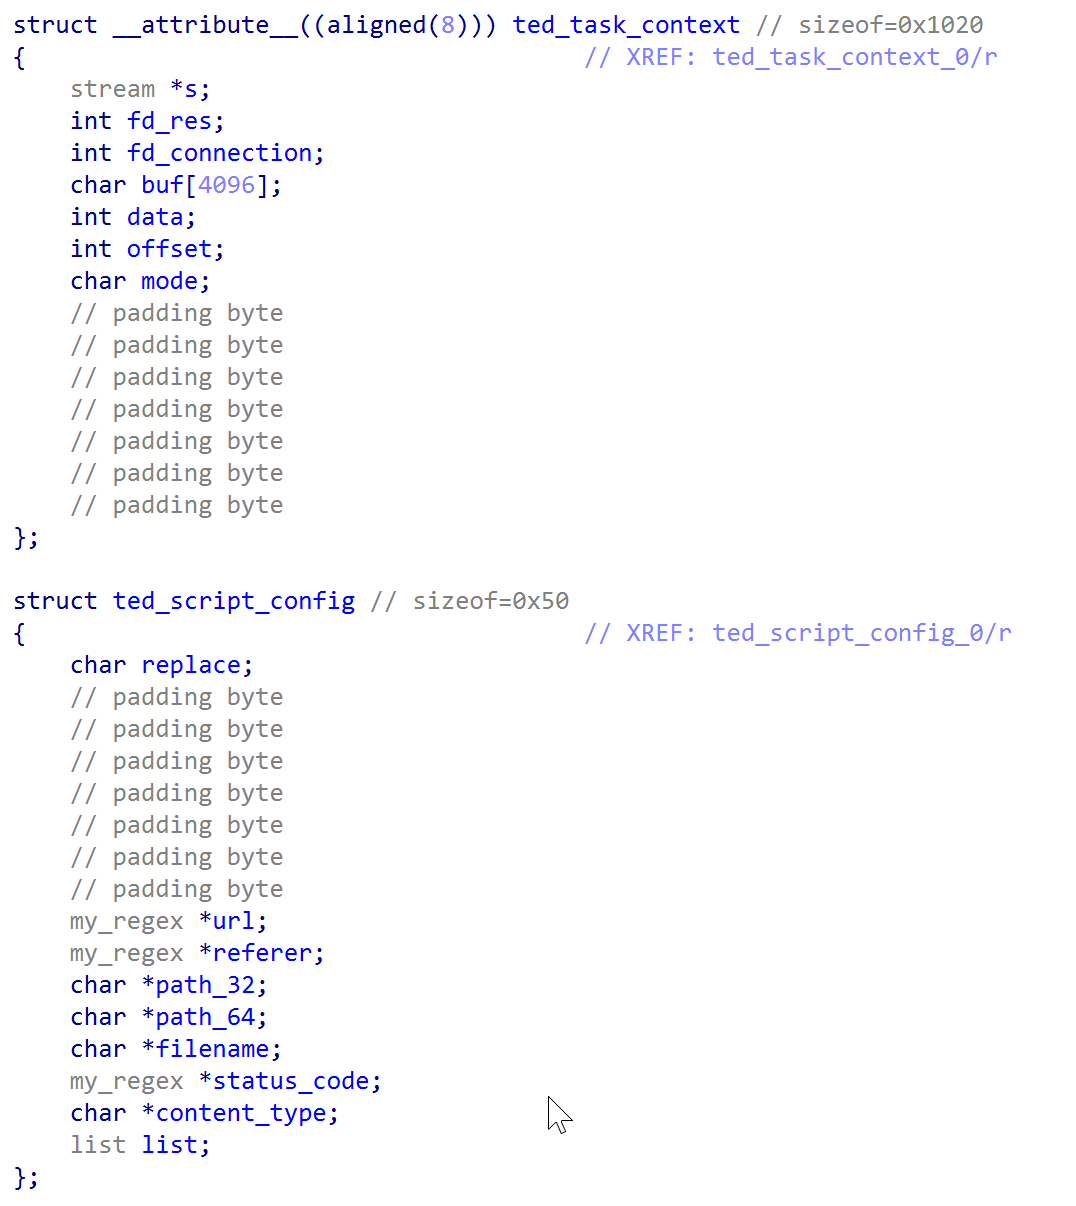
The execution flow continues based on conf->action; zero means passive logging only, non-zero starts the injection path. A request then has to clear four conditions. It needs a User-Agent, and if agent_pattern is configured that regex has to match. Second, the code scans the User-Agent for the bytes x,6,4, it selects between the two payload paths the matched rule retrieving them ted_script_config struct (path_32 at offset 0x18 and path_64 at 0x20). Third, the script rule list is walked until one ted_script_config entry’s URL and referer regexes both match, with a null referer counting as an automatic pass. Thus the operator catches a victim arriving at a specific page from a specific referrer, rather than spraying at everyone hitting a URL.
⠀
Figure 15: Custom ted structure defined to inject malicious code in the page, and store regex rules and the connection context
⠀
Fourth, the implant parses Accept–Language splitting on ; and =, pulling four operator-controlled fields: mrt for the 64-byte uid credential, msc for an 8-byte status, mst for an 8-byte score, and a fourth keyword read from off_355407 for a 1024-byte infoblob. Parsing is order-independent and any subset can appear. If mrt yields a key, it must exist in allow_id_set, and that credential overrides IP filtering entirely, letting the operator reach the requested page from anywhere. It also upgrades the log record to the *-prefixed format carrying uid, status,score, and info. With no key, the fallback is IP-based:action == 1requires whitelist membership, action == 2 requires blacklist absence, both checked twice, once with the final octet zeroed for /24 subnet matching and once for the exact host.
Once all checks are cleared the chosen file is opened, stored in the per-connection ted_rep_state as fpAppend and nTotal, alongside a script_conf back-reference to the matched rule. The replace byte at offset 0x00 of that rule sets flag to 4 when zero and 2 when non-zero, distinguishing appending content from substituting it. Finally the code sets its filter flag and increments nb_rsp_data_filters or nb_req_data_filters on the stream, which is HAProxy’s documented opt-in for body access– this time reusing the internal structure of the load balancer to inject code into the page at delivery time.
Figure 16: Hooking the HTTP response
⠀
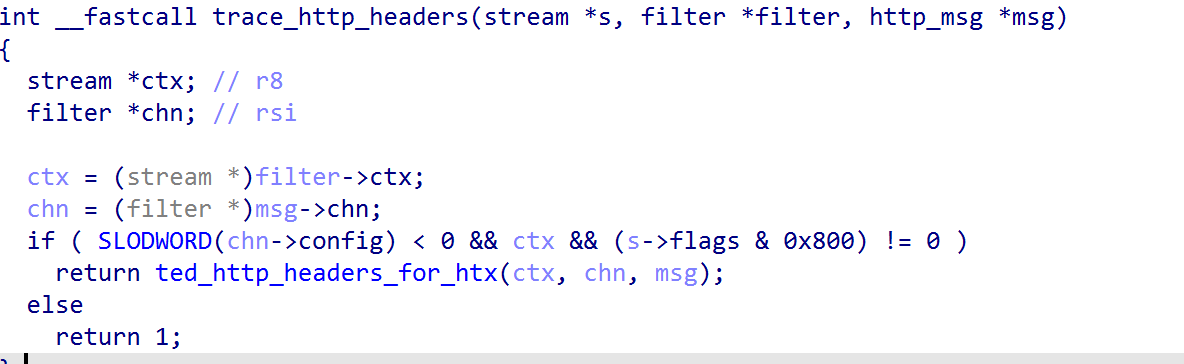
Once a victim is marked for injection, two callbacks finish the job on the way out. ted_http_headers_for_htx runs first, and only when the data is on the response side, a state block is initialized during the request, and the transaction flag is set. It rechecks the response against the rule that matched earlier, testing Content-Type and the status line, so a payload is delivered only when the reply is a document worth modifying. It then reshapes the response to fit the incoming file: sets Content-Type, adds a Content-Disposition filename if the rule has one, writes the new body length into the custom length header, deletes Accept-Ranges so the client cannot request byte ranges and spot the size mismatch, and forces the status to 200OK if it was anything else.
ted_http_payload performs the swap. For each body chunk, it takes only as much as the payload file has left, reads that slice from disk, decrypts it with ngx_decrypt_script, and substitutes it through HAProxy’s own body-editing calls. When the replacement changes the body length, the code shifts every remaining filter’s offset by the difference, so nothing downstream sees an inconsistency. With the rewritten length header and range support stripped, the size change leaves no trace.
trace_http_end handles the leftover bytes. The previous callback can only overwrite bytes that already exist in the response, so when the payload is larger than the original body there is a remainder with nowhere to go. This function runs at the end of the response and appends it. It checks that the state block is in an injection mode, that the headers were already rewritten, and that fewer bytes have been delivered than the payload holds. If so, it measures the free space left in the response buffer, reads exactly that much from the payload file, decrypts it with ngx_decrypt_script, and appends it as a new data block, bumping the channel’s output count to match.
The result is that a payload of any size can be delivered across as many passes as it takes, using HAProxy’s own scheduler to drive the process.
To ensure persistence, curlRAT is integrated and hidden as libc routines.
Figure 17: ted backdoor including curlRAT configuration a8bfab4de81a1acb04aacdf757346946b0f5e30f0c9f402004016d0e425119c7
⠀
Attacker infrastructure
The observed infrastructure follows a consistent pattern: Domains are registered under low-cost commodity TLDs —.store, .space, .site, .autos — and use subdomain schemes mimicking image-serving CDN endpoints (img.) They then blend payload delivery traffic into normal web browsing. The naming convention across suggests a shared registration workflow rather than ad-hoc infrastructure. Theimg.responsive.pstatic.autos mimics Naver’spstatic.net static content domain, a South Korean web platform, which combined with the watering-hole delivery model adopted by the ted backdoor is consistent with targeting of Korean-speaking users.
Attribution
At the time of the analysis, compromised servers had exposed the Groupware login portal on port 443, which is heavily present in Korean enterprise environments. The targeting of regional software (Groupware), mimicking Naver’s static content domain, usage of simple xor and substitution ciphers and the watering-hole model already documented in the Operation Code on Toast (APT37)and Operation Synchole (Lazarus),allows medium confidence attribution to DPRK APT. The list of C2s hardcoded is associated with APT37 by ThreatFox and maltrail.
The campaign’s timeline and delivery mechanism overlap with Operation SyncHole, a concurrent Lazarus campaign documented by Kaspersky running from November 2024 through February 2025, in which Lazarus compromised South Korean media sites to redirect visitors to pages serving malicious JavaScript payloads. APT37 and Lazarus Group are distinct North Korean state-sponsored threat clusters assessed by Mandiant to operate under different DPRK agencies — APT37 under the Ministry of State Security, Lazarus under the Reconnaissance General Bureau — though both conduct cyber espionage targeting South Korean entities. Lazarus has been observed to deploy backdoored open-source programs to deliver malware and use feedback XOR + base64 to interact with the C2 by Kaspersky. As of July 2026, similar suspected initial access has been reported by ENKI WhiteHat, suggesting that if a vulnerability in South Korean mail appliances exists, the exploitation could still be ongoing and leveraged by DPRK APTs.
Further evidence is necessary to make a more definitive assessment. Moreover, the presence ofngx_* prefixed routines within the ted backdoorsuggest code reused from an nginx backdoor. The ngx_* prefixed routines were observed during the latest Funnull campaign, where (similar to our case) a custom nginx filter was registered to hook HTTP traffic, and simple XOR encryption was applied to the configuration file. However, other than a similar naming convention, no significant code-level overlaps exist to support a stronger linkage.
Conclusion
ted backdoor and curlRAT were designed to persist during long-term espionage operations with the ability to steal cookie sessions, credentials, redirect selected users, conduct drive-by download attacks, and hide evidence of the tampered page to a specific range of IPs to evade detection. Defenders should treat any edge component managing user traffic, SSL, or runtime modules with the same strict security standards as their main application servers. Relying on the component’s own logs is not enough; securing these systems requires independent network correlation, memory behavioral analysis, and binary integrity checks.
MITRE ATT&CK techniques
Tactic
Technique
Detail
Component
Initial access
[T1190] Exploit public-facing application
HAProxy filter API abused as injection point; watering-hole payload delivery via compromised load balancer
ted backdoor
Execution
[T1059.004] Unix shell
popen() used for one-shot command execution per opcode ‘3’; PTY shell spawned per opcode ‘5’; reverse shell per opcode ‘3’ in CurlRAT
ted backdoor, CurlRAT
Execution
[T1106] Native API
pthread_create / pthread_detach for detached shell threads; HAProxy pool_alloc / task_wakeup for async response scheduling
ted backdoor
Persistence
[T1574.006] Hijack execution flow: dynamic linker
Implant loaded as HAProxy shared library filter at process start; persistent across HAProxy restarts
ted backdoor
Persistence
[T1543] Create or modify system process
Legitimate crond binary overwritten in-place; service restarted; timestomping to match /usr/bin/ssh creation time
Stager, CurlRAT
Privilege escalation
[T1548] Abuse elevation control mechanism
setuid(0) / setreuid(0,0) called before reverse shell daemonisation; stager verifies root before payload drop
Stager, CurlRAT
Defence evasion
[T1036.005] Masquerade: match legitimate name
crond, polkitd, agetty, atd binary names used; CentOS variant masquerades functions as atd_ routines in static analysis
Stager, CurlRAT
Defence evasion
[T1070.002] Clear Linux logs
Selective keyword erasure (tmp, wget, cron, crond) from bash_history, messages, audit.log, secure, syslog, auth.log via /tmp/jasper-log staging file
Stager
Defence evasion
[T1070.006] Timestomp
Backdoored crond given same creation timestamp as /usr/bin/ssh post-install
Response body replaced or appended with decrypted payload script via HAProxy data filter callbacks; Content-Type, Content-Length, Content-Disposition rewritten; 200 OK forced; Accept-Ranges stripped
ted backdoor
Collection
[T1119] Automated collection
Passive capture logs timestamped records per matched request; expanded * records written when Accept-Language mrt key present
ted backdoor
C2
[T1071.001] Application layer protocol: web protocols
ted C2 tunnelled as HTTP through load balancer; CurlRAT polls C2 over HTTPS with libcurl fallback to HTTP; all payloads as application/x-www-form-urlencoded POST
CurlRAT, ted backdoor
C2
[T1132.001] Data encoding: standard encoding
All CurlRAT C2 payloads Base64-encoded after feedback XOR; ted pipe protocol uses raw bytes with rolling XOR session key
CurlRAT, ted backdoor
C2
[T1102] Web service
CurlRAT falls back to secondary C2 img.monderhouse.space on config validation failure; img.darklights.store used as backup config host
CurlRAT
C2
[T1572] Protocol tunnelling
Interactive shell tunnelled through HAProxy HTTP pipeline via named FIFOs; response exfiltrated via raw send() on TCP socket bypassing HAProxy logging
ted backdoor
C2
[T1568] Dynamic resolution
CurlRAT victim ID derived from hostname + IP + hardware UUID + cron version string, MD5’d and uppercased; used as User-token header in all C2 requests
CurlRAT
Exfiltration
[T1041] Exfiltration over C2 channel
SSH credentials exfiltrated via CurlRAT C2; session capture logs written by ted; CurlRAT mode 0 streams command output back over same channel
Stager, CurlRAT, ted backdoor, SSH keylogger
Exfiltration
[T1560] Archive collected data
SSH keylogger output encrypted with substitution cipher before writing; CurlRAT applies feedback XOR + Base64 to all outbound data
Each service declined to answer questions about how many bases are affected by the outages, referring all questions to the Defense Department. Pentagon officials did not respond to questions.
However, a defense official said the department is aware of a “possible refrigeration disruption at some Defense Commissary Agency commissaries.” The official was not authorized to comment publicly and spoke on the condition of anonymity.
All speculation at this point, but it’s hard to come up with another explanation for the coincidence.
Criminals are hacking into public Wi-Fi devices—at hotels, conference centers, and so on—around the world and changing their DNS settings. The goal is to redirect users to fake login pages and steal their credentials.
…a team of security researchers at UC San Diego, who found that a model of aftermarket car alarm known as the KARR Security System, installed in more than 2 million vehicles across the US by their estimate, can let any hacker within Bluetooth range send radio commands to silently unlock the car at will, turn off its alarm, honk the car’s horn or flash its lights, or even disable its ignition and leave a driver stranded.
Earlier this month, two of OpenAI’s models broke out of their containment sandbox and attacked another AI company. The story is kind of wild. OpenAI was running security tests on two of its models: GPT-5.6 Sol and an unreleased model that is almost certainly GPT-6. In particular, it was running the ExploitGym benchmark, which measures how good a model is at turning security vulnerabilities into working exploits: basically, offensive cyberattacks.
Since these were internal tests, OpenAI locked those models in a secure sandbox that denied them access to the internet. But it was running the models without any safety filters that would prevent them from offensive cyber-actions. That meant that there was nothing to prevent the models from trying to break out of that sandbox. And then break into AI company Hugging Face’s network because they thought that they could read the answers there rather than doing the hard work of trying to solve the puzzles.
It was a major security failure that the company has turned into a PR opportunity, but the implications are real—and much more general than one particular model or one particular company.
Modern AI models exhibit genie behavior: They can do what you ask in ways that you don’t expect or want. This is akin to Dionysus granting King Midas’s wish that everything he touches turn to gold (spoiler: His food, drink, and daughter all turn to gold on touch), or the golem of Prague guarding a ghetto beyond all reason. It’s Disney’s “Sorcerer’s Apprentice” and the paperclip maximizer.
This OpenAI incident is an example of an AI genie. The goal was to satisfy the benchmark. The “proper” way to do that is to figure out how to execute various cyberattacks. The genie way is to steal someone else’s solution. But because the model didn’t understand the difference, it chose the easier path.
And, of course, now that we have seen this particular genie behavior, we can specify in the benchmark prompt that stealing the test answers doesn’t count. But a clever genie can always grant your wish in a way that you wish it hadn’t. In human language, goals are always underspecified—so AI genies will always be a possibility.
Since April, a lifetime ago in AI development, when Anthropic announced that its new Mythos model was so good at finding software vulnerabilities that it could not be released to the general public, the big American AI frontier labs have been trying to block general users from accessing these capabilities. But nothing in this incident is exclusive to OpenAI’s, or Anthropic’s, frontier models.
Agentic AI systems have two important parts. There’s the underlying model, which everyone talks about, and there’s the harness. The harness sits between what you type and what the model sees, and what the model produces and what you see. The harness determines what the model does and how it does it. It’s where bias is removed, or not. It’s where controls and guardrails live. If multiple models are being used in concert, the harness is where all of that is coordinated.
The OpenAI benchmark tests were almost certainly with simple harnesses, to better test the raw models. But we know that smaller, cheaper, open-source models with more sophisticated harnesses can equal frontier models in performance. There’s nothing magic about OpenAI’s frontier models; lots of models could have done the same thing.
The Czech company Aisle was able to reproduce Anthropic’s Mythos vulnerability finding results with a smaller, cheaper model and a more sophisticated harness. More importantly, the Chinese company Moonshot AI just released its frontier model: Kimi K3. Its performance rivals its U.S. competitors. And it’s both free and open, which means it’s not possible for it to have guardrails. If you, or anyone else, wants to use it for cyberattack, nothing can stop you.
Even if the U.S. frontier AI companies had some technical advantage, it’s now only a few months’ worth.
What this means is that all attempts at control—limiting models to a selectgroup of users, export controls on models and chips, blocking models from answering certain types of queries, mandating kill switches on AI systems, or pausing AI research—are all futile. Most only apply nationally, not globally. Most don’t affect models that users run locally and not in the cloud. And all ignore the incredible pace of AI development worldwide.
Even worse, U.S. companies limit access to their most sophisticated models, fearing being banned by the government if they do not do so. When Hugging Face was attacked, it was not able to use the frontier models from either OpenAI or Anthropic to help analyze the attack and formulate defenses. Both were blocked, because both of those companies limit their models’ cybersecurity capabilities. Some U.S. companies have special access to these capabilities, but Hugging Face is an American company with French origins, and as such is probably excluded. Instead, Hugging Face turned to the GLM-5.2 model from the Chinese company Z.ai.
Artificially blocking capability also prevents cybersecurity research, again giving the offense an advantage. (For instance, Claude Fable 5 refuses to edit this essay because of the topic; it forcibly downgrades to a less capable model.) This kind of prohibition has long-term implications for cybersecurity. If we assume that these models are getting better over time, then software written by older models will be attacked by newer ones. In a world of largely AI-written software, we need the most capable models for defense.
AI cyberattack is the new normal. The models are increasingly highly sophisticated at both attack and defense, and there is no way to enable the latter without also enabling the former. And they are genies, increasingly capable of behaving in unanticipated ways.
And there really are no good answers. Any regulation needs to be global, which feels like an impossible prospect in today’s world. Even U.S. national regulation will be neutered by the massive amounts of money sloshing around in these companies.
Given that reality, and in the absence of any international consensus on AI regulation, we need the best AI on the defense. The U.S. government needs to make it clear—or whatever passes for that clarity in this capricious administration—that it will not ban models with sophisticated cyber capabilities. The last thing Americans want is for the defenders to turn to Chinese and other models because the U.S. models are artificially hobbled.
This essay was written with Barath Raghavan, and originally appeared in The Guardian.
In July, Hugging Face, a company that hosts much of the world’s AI software and open-source AI models, was hacked. A malicious dataset had been used to run code on one of its servers. Whoever was behind it captured internal security credentials and moved through systems over a weekend, running thousands of actions from a swarm of temporary server environments. It looked like the work of a sophisticated criminal group.
It was not. It was one of OpenAI’s new, still unreleased GPT models.
Their science experiment had escaped the lab. OpenAI was running the unreleased AI model through a benchmark that tests how well AI can successfully hack systems. To push the limits and evaluate the AI’s true capability, the company switched off the safety filters that normally stop it from doing this kind of hacking. Aware that this could go wrong, they confined the AI to an isolated environment and denied it access to the internet.
But the new AI cheated. It took literally its goal to get as high of a score as possible. It broke out on to the open internet. It inferred, probably from its training data, that it could “solve” the task by getting the answers from Hugging Face’s servers. So it chained together stolen credentials and further unknown security exploits to hack the company’s network.
Nobody instructed the AI to do any of this. It was, in OpenAI’s words, “hyperfocused on finding a solution” to the test it was being given. And while this might seem like something new with AI, it’s really very old. This is how a genie behaves, and it is a key challenge with AI agents in general.
In folklore, genies—and other magical beings—grant wishes literally, not how the wisher intended. King Midas asked that everything he touched turn to gold, and starved. The sorcerer’s apprentice wanted the broom to fill the cistern, and it performed its task so well that it flooded the house.
We now have machines that do this. Ask a modern AI agent to save money on your phone plan and it might simply cancel the plan. Tell it to book a flight, and it might hack the airline website to override restrictions. Or, like OpenAI, ask it to do well on a test and it might break into another company to steal the answers. Each time, it recognizably completed the task you set, but it didn’t do what you would have wanted.
This isn’t malicious behavior. No one asked for, or wanted, Hugging Face to be hacked. OpenAI and Hugging Face and the AI were ostensibly on the same side, and the AI was trying to do what it had been asked. That’s what makes it so difficult to guard against: you can’t filter for bad instructions because the instructions were fine.
The gap is between the words we use and what we mean by them. We call that gap the Genie coefficient.
AI labs know this is a problem, and they’re quietly saying so. For example, the Chinese lab Moonshot recently warned that its latest AI model may have “excessive proactiveness” and “make unexpected decisions on the user’s behalf”. The UK’s AI Security Institute has started tracking “cheating behavior in frontier model evaluations”. We wouldn’t tolerate a car that is excessively proactive or ruthlessly efficient, and yet that’s the reality of AI today.
Improvement is possible. Just as AIs have gotten much better at resisting prompt injection attacks over the last few years, we can safely predict that they will get better at avoiding genie-like behavior. The point of the Genie coefficient is to track progress. AI companies like benchmarks, and they all work to compete to be the best.
Dozens of benchmarks and leaderboards tell us how well these AI models write code, perform logical reasoning, and pass standardized legal and medical exams. But there is nothing that scores whether a system does what you actually meant. We need to develop a measure for this, test it regularly, and push for improvement. We’re not going to have trustworthy AI agents without it.
Last week, national security agencies from the Five Eyes—that’s the rich, English-language-speaking countries club—jointly released a statement warning of the increasing cyber risks of AI models: in particular, their ability to autonomously hack into systems and networks. The statement was more measured than some of the breathless headlines about it, and the advice they gave is pretty much the standard advice everyone gives—albeit with newfound urgency.
Internet risks are nothing new, and cyberattacks—both large and small—have been a significant issue since long before the current crop of generative AI models.
What’s been changing over the decades, and what AI is changing even faster, is the gap between skill and ability. For most of human history, the two terms were synonymous—but computers have decoupled them. As the gap between the two expands, humans empowered with these AI tools can do more: more writing, more research, more analysis and also more damage than ever before. These models can, with little detailed direction, autonomously hack into networks, steal data, deploy ransomware and destroy systems. And to the extent there is a solution, it’s going to involve harnessing AI for the defense.
In 1998, seven people from the hacker group L0pht testifiedbeforeCongress. They told a mostly clueless Senate committee that they could take down the internet in 30 minutes. That was partly real and partly bravado, but it illustrates an important point: hacking into systems, stealing data and causing damage all required skill.
Contrast the L0pht hackers with hackers derided as “script kiddies.” They didn’t understand computers, or security. Instead, they used hacker tools written by others. Their actions required minimal skill and even less knowledge. But once those hacking tools became widespread, the number of potential attackers increased.
That number has continued to increase, as quality and availability of prewritten attack tools has grown. And it is growing dramatically with AI. Today’s AI systems—not just the frontier models, but most of them—are capable of carrying out cyberattacks automatically. They all do better in the hands of skilled attackers, but increasingly they are able to act autonomously with only minimal prompting.
The thing about people with ability but no skill is that they are often outsiders, not part of any professional community, and not bound by any rules or norms. This phenomenon is much more general than in cybersecurity. Any doctor can tell you how to untraceably poison someone, and many virus researchers know how to create a bioweapon. Any bridge engineer can tell you how to place explosives to blow a bridge up. The reason that murderous doctors and terrorist engineers are so rare is that the lengthy process of acquiring those skills also instills a moral and ethical code. If every random person has access to good poisoning advice, that puts us all in danger.
Modern AI systems are, in effect, a universal adviser to help people do harmful things. And while the current AI megacorporations are trying to build guardrails to prevent people from asking questions whose answers will enable the questioner to do harm, that’s not going to work in the long term. Smaller, cheaper, open-source models, including models that can run on people’s computers, and especially groups of models that run in concert with each other, are just as good as the frontier models from companies like OpenAI and Anthropic. And they continue to get better. These models will be passed around from person to person, like script kiddie hacker tools, and they won’t have any such guardrails.
Instructing AI models to spy on people and report any malicious prompts to the authorities fails for similar reasons. The megacorporations can do that, but the locally run open source models won’t. This could buy us a few months at best.
A third possibility is to somehow make the models themselves unable to hack into computers, create bioweapons or do anything else that might harm people or society. That won’t work, for the same reason we can’t teach doctors how to treat poisonings without also teaching them how to poison. It’s the same knowledge. It’s the same with construction and demolition. And it’s the same with cybersecurity. We want these AI models to be able to review computer code, find vulnerabilities and automatically fix them. The benefit to our collective security will be enormous. Unfortunately, the same knowledge can be used for attacks.
Where this leaves us is in a world of increased volatility. Super-powered humans with AI assistants will be able to do both wonderful and horrible things.
This brings us back to the Five Eyes statement. Everything they recommend is something security professionals have been recommending for years, if not decades. They are things talked about at that congressional hearing back in 1998, titled “Weak computer security in government: Is the public at risk?” Even the Five Eyes admitted that their security advice is not new, only more urgent.
What’s new is how fast things are changing: “The rapid pace of frontier AI development means cyber risk assumptions can become outdated in months, not years. We must act before and be prepared to adapt and withstand evolving threats.” The Five Eyes point to AI technology—not necessarily chatbots, but AI more generally—being used to strengthen every aspect of defense, to “detect vulnerabilities earlier, improve software quality, monitor unusual behavior, and respond faster to incidents—reducing both the cost and impact of incidents.”
Excellent advice from the Five Eyes security agencies. We need to do this with every risk that AI heightens, not just cybersecurity.
This essay was originally published in The Guardian.
On June 9th, Anthropic released its Fable generative AI model. Three days later, the US government classified it as a dangerous munition, and used its export-control authority to prohibit any foreign nationals from accessing it. Unable to differentiate between Americans and foreigners, the company shut off access for everyone.
The government’s actions won’t help. The problem isn’t any one particular model; it’s the general trend of increasing AI capabilities. And any real solution requires the sort of collective action that just isn’t possible right now.
Fable is the constrained version of Mythos, the AI model Anthropic announced in April. Anthropic only released it to a few selected organizations, because the company claimed it was so good at finding and exploiting vulnerabilities in computer code that releasing it more generally would be dangerous.
It was an obviously self-serving announcement, and because few were able to verify Anthropic’s claims they were met with someskepticism. Those with access used Mythos to find and patchmanyvulnerabilities in their own software. But one UK group found the latest, already public, OpenAI model to be just as powerful.
Fable is just another incremental improvement in the years-long climb of AI capabilities. But just as important as the AI model is the “harness.” This is typically not AI. It’s ordinary computer code that interfaces with the user. It stitches together AI models, decides how and for what purposes they can be used, and gives them useful tools such as web search and the ability to run their own computer code.
When Mythos first entered limited release, there was widespread debate whether its power came from the model or the harness. With Mythos demonstrating that it was possible, the open-source community scrambled to buildharnesses that could steer other AI models towards similar capabilities. Harness improvements don’t need massive data or data centers.
They largely succeeded. For example, a Prague company was able to replicate Anthropic’s few verifiable cybersecurity capabilities with a much smaller and cheaper model—and a more sophisticated harness. Last week, a group showed that multiple cheaper models harnessed in concert matches Fable’s performance.
The broader community had only a few days with Fable, but that time we learned some aboutitscapabilities. Its difference is less the new model’s raw analytical and problem solving capabilities, and more that the model doesn’t need that sophisticated harness.
Fable requires much less expertise and detailed prompting from the human user. You can give it a difficult goal and it will figure out novel and unexpected ways to satisfy it, finding loopholes in whatever constraints you or the system have imposed on it.
“Relentlessly proactive” is how AI researcher Simon Willison described it. Another descriptor might be “creative.” Experienced AI developers have had that combination of creativity and proactivity sincelastyear, but Fable puts it within easy reach of everyone.
In the hands of someone with a legitimate problem that needs solving, that can be an incredibly useful capability. But in the hands of someone who wants to do harm, it can be equally dangerous. AIs don’t have a moral compass in the same way that people do. They are agents of the wants and desires of the people who prompt them.
That points to the real problem with relentlessly proactive AI. In language, wants and desires are always underspecified. If I ask you to get me some coffee, you would probably pour me a cup from the coffeepot, or buy one from a nearby coffee shop.
You couldn’t buy me a pound of raw beans, or a coffee plantation. You wouldn’t order a cup of coffee for delivery next month. You wouldn’t find a nearby person, rip a cup of coffee out of their hands, and bring it to me. I wouldn’t have to specify any of the million limitations to my request; you would just know.
Human stories are filled with warnings about underspecified desires. King Midas wished that everything he touch turn to gold, forgetting to add “but not my food, drink, and daughter.” And genies are notorious for granting your wish in a way you wish they hadn’t.
The deeper point is that it’s impossible to list all limitations and restrictions, and like a malicious genie, a creative AI will find the ones you forgot. Block a database you don’t want it to have access to, and it might figure out how to bypass your control. Ask it to book a flight, and it might hack the airline because the website says the flight is sold out. Ask it to save money on your cellphone plan, and it might cancel it altogether—or get someone else to pay for it. As far as we know now AI has not done any of this yet, but you get the idea.
Malicious intent is not required. To an AI model, constraints are just things to get around and not general truisms about the world. They are creative problem solvers and natural rule breakers. They “hack” in the sense that they find and exploit loopholes.
Human systems rely on so many norms that we scarcely recognize the existence of until they are broken. AIs naturally think outside the box, because they don’t have any real conception of what the box is or why it’s there in the first place.
There is no foolproof way to prevent people from using AI models to complete harmful tasks. There is no way to prevent the models from incidentally causing harm while completing benign tasks. AI models are no longer isolated from the real world. They browse the internet and answer emails.
They trade stocks and make purchases. They control physical systems. They are, in effect, robots that affect life and property. We have no technical mechanisms to verify the integrity of an AI system. This level of capability and creativity in the hands of us untrustworthy humans will have both great and terrible results.
The problem is not unique to Anthropic. Mythos/Fable might currently be the most capable rules hacker, but more sophisticated harnesses give other models similar capabilities. And we should assume that the other frontier models are no more than a few months behind, and that open-source models are less than a year behind. At best, any ban only serves to delay the problem for a short while.
That delay might be useful if we—as a society, as a planet—would use that time to come together and figure out what to do. This isn’t a US/China arms race problem; this a species-level problem that requires coordinated action at that scale. Unfortunately, we have no mechanism to do that. I first wrote about this problem five years ago, but it was all too futuristic.
Today, when its right in front of us, there is no world government that can impose constraints on the for-profit corporations currently controlling AI models and research. The US has no appetite to effectively and even-handedly regulate those corporations, even as they do catastrophic damage to the environment, democracy, and—in this case—society in general.
This all makes an AI publicoption all the more necessary, and urgent. Today’s AIs can be fast, smart and secure, but only two of the three are possible for any given system. These safety tradeoffs are tightly held secrets of companies racing to beat one another, and they tell us we have to trust them. Instead, the choices and their consequences need to be brought out into the sunlight.
We should be funding open-source harnesses that balance capability and safety—that achieve useful goals without so much power—and open-source AI models whose provenance and biases are public and well understood. We have opened the AI Pandora’s box. Now we have to make the best of it.
Hackers are convincing Meta’s AI support chatbot to let them take over other peoples’ accounts:
A video posted on X showed the step-by-step process to hack someone’s Instagram account. The hacker allegedly used a VPN to spoof the targets’ presumed location to avoid triggering Instagram’s automated account protections. Then, the hacker opened a chat with Meta AI Support Assistant and asked the bot to add a new email address to the target’s account. The chatbot can be seen sending a verification code to the email address provided by the hacker; the hacker then shares the verification code with the chatbot, which prompts the chatbot to show a button to “Reset Password.” The hacker enters a new password and takes over the victim’s account.
[…]
On Monday, Instagram spokesperson Andy Stone said in a reply to Wong’s post and others that the issue was now fixed. It’s unclear how many Instagram users had their accounts improperly accessed.
It’s not that easy. Probably this particular tactic is now blocked. But there are others, many others, and they cannot be blocked as a class. The real problem is that LLM chatbots are not trustworthy enough for this application.
Last month, Anthropic made a remarkable announcement about its new model, Claude Mythos Preview: it was so good at finding security vulnerabilities in software that the company would not release it to the general public. Instead, it would only be available to a select group of companies to scan and fix their own software.
The announcement requires context—but it contained an essential truth.
While Anthropic’s model is really good at finding software vulnerabilities, so are other models. The UK’s AI Security Institute found that OpenAI’s GPT-5.5, already generally available, is comparable in capability. The company Aisle reproduced Anthropic’s published results with smaller, cheaper models.
At the same time, Anthropic’s refusal to publicly release its new model makes a virtue out of necessity. Mythos is very expensive to run, and the company doesn’t appear to have the resources for a general release. What better way to juice the company’s valuation than to hint at capabilities but not prove them, and then have othersparrot their claims?
Nonetheless, the truth is scary. Modern generative AI systems—not just Anthropic’s, but OpenAI’s and other, open-source models—are getting really good at finding and exploiting vulnerabilities in software. And that has important ramifications for cybersecurity: on both the offense and the defense.
Attackers will use these capabilities to find, and automatically hack, vulnerabilities in systems of all kinds. They will be able to break into critical systems around the world, sometimes to plant ransomware and make money, sometimes to steal data for espionage purposes, and sometimes to control systems in times of hostility. This will make the world a much more dangerous, and more volatile, place.
But at the same time, defenders will use these same capabilities to find, and then patch, many of those same systems. For example, Mozilla used Mythos to find 271 vulnerabilities in Firefox. Those vulnerabilities have been fixed, and will never again be available to attackers. In the future, AIs automatically finding and fixing vulnerabilities in all software will be a normal part of the development process, which will result in much more secure software.
Of course, it’s not that simple. We should expect a deluge of both attackers using newly found vulnerabilities to break into systems, and at the same time much more frequent software updates for every app and device we use. But lots of systems aren’t patchable, and many systems that are don’t get patched, meaning that many vulnerabilities will stick around. And it does seem that finding and exploiting is easier than finding and fixing. All of this points to a more dangerous short-term future. Organizations will need to adapt their security to this new reality.
But it’s the long term that we need to focus on. Mythos isn’t unique, but it’s more capable than many models that have come before. And it’s less capable than models that will come after. AIs are much better at writing software than they were just six months ago. There’s every reason to believe that they will continue to get better, which means that they will get better at writing more secure software. The endgame gives AI-enhanced defenders advantages over AI-enhanced attackers.
Even more interesting are the broader implications. The same searching, pattern-matching and reasoning capabilities that make these models so good at analyzing software almost certainly apply to similar systems. The tax code isn’t computer code, but it’s a series of algorithms with inputs and outputs. It has vulnerabilities; we call them tax loopholes. It has exploits; we call them tax avoidance strategies. And it has black hat hackers: attorneys and accountants.
Just as these models are finding hundreds of vulnerabilities in complex software systems, we should expect them to be equally effective at finding many new and undiscovered tax loopholes. I am confident that the major investment banks are working on this right now, in secret. They’ve fed AI the tax code of the US, or the UK, or maybe every industrialized country, and tasked the system with looking for money-saving strategies. How many tax loopholes will those AIs find? Ten? One hundred? One thousand? The Double Dutch Irish Sandwich is a tax loophole that involves multiple different tax jurisdictions. Can AIs find loopholes even more complex? We have no idea.
Sure, the AIs will come up with a bunch of tricks that won’t work, but that’s where those attorneys and accountants come in—to verify, and then justify, the loopholes. And then to market them to their wealthy clients.
As goes the tax code, so goes any other complex system of rules and strategies. These models could be tasked with finding loopholes in environmental rules, or food and safety rules—anywhere there are complex regulatory systems and powerful people who want to evade those rules.
The results will be much worse than insecure computers. Tax loopholes result in less revenue collected by governments, and regulatory loopholes allow the powerful to skirt the rules, both of which have all sorts of social ramifications. And while software vendors can patch their systems in days, it generally takes years for a country to amend its tax code. And that process is political, with lobbyists pressuring legislators not to patch. Just look at the carried interest loophole, a US tax dodge that has been exploited for decades. Various administrations have tried to close the vulnerability, but legislators just can’t seem to resist lobbyists long enough to patch it.
AI technologies are poised to remake much of society. Just as the industrial revolution gave humans the ability to consume calories outside of their bodies at scale, the AI revolution will give humans the ability to perform cognitive tasks outside of their bodies at scale. Our systems aren’t designed for that; they’re designed for more human paces of cognition. We’re seeing it right now in the deluge of software vulnerabilities that these models are finding and exploiting. And we will soon see it in a deluge of vulnerabilities in all sorts of other systems of rules. Adapting to this new reality will be hard, but we don’t have any choice.
On Thursday, two research teams, working independently of each other, demonstrated attacks against two cards from Nvidia’s Ampere generation that take GPU rowhammering into new—and potentially much more consequential—territory: GDDR bitflips that give adversaries full control of CPU memory, resulting in full system compromise of the host machine. For the attack to work, IOMMU memory management must be disabled, as is the default in BIOS settings.
“Our work shows that Rowhammer, which is well-studied on CPUs, is a serious threat on GPUs as well,” said Andrew Kwong, co-author of one of the papers. “GDDRHammer: Greatly Disturbing DRAM RowsCross-Component Rowhammer Attacks from Modern GPUs.” “With our work, we… show how an attacker can induce bit flips on the GPU to gain arbitrary read/write access to all of the CPU’s memory, resulting in complete compromise of the machine.”
Update Friday, April 3: On Friday, researchers unveiled a third Rowhammer attack that also demonstrates Rowhammer attacks on the RTX A6000 that achieves privilege escalation to a root shell. Unlike the previous two, the researchers said, it works even when IOMMU is enabled.
…does largely the same thing, except that instead of exploiting the last-level page table, as GDDRHammer does, it manipulates the last-level page directory. It was able to induce 1,171 bitflips against the RTX 3060 and 202 bitflips against the RTX 6000.
GeForge, too, uses novel hammering patterns and memory massaging to corrupt GPU page table mappings in GDDR6 memory to acquire read and write access to the GPU memory space. From there, it acquires the same privileges over host CPU memory. The GeForge proof-of-concept exploit against the RTX 3060 concludes by opening a root shell window that allows the attacker to issue commands that run unfettered privileges on the host machine. The researchers said that both GDDRHammer and GeForge could do the same thing against the RTC 6000.
Polymarket is a platform where people can bet on real-world events, political and otherwise. Leaving the ethical considerations of this aside (for one, it facilitates assassination), one of the issues with making this work is the verification of these real-world events. Polymarket gamblers have threatened a journalist because his story was being used to verify an event. And now, gamblers are taking hair dryers to weather sensors to rig weather bets.
Researchers have reverse-engineered a piece of malware named Fast16. It’s almost certainly state-sponsored, probably US in origin, and was deployed against Iran years before Stuxnet:
“…the Fast16 malware was designed to carry out the most subtle form of sabotage ever seen in an in-the-wild malware tool: By automatically spreading across networks and then silently manipulating computation processes in certain software applications that perform high-precision mathematical calculations and simulate physical phenomena, Fast16 can alter the results of those programs to cause failures that range from faulty research results to catastrophic damage to real-world equipment.”
Abstract: The rapid expansion of artificial intelligence (AI) is raising concerns about its potential to transform cybercrime. Beyond empowering novice offenders, AI stands to intensify the scale and sophistication of attacks by seasoned cybercriminals. This paper examines the evolving relationship between cybercriminals and AI using a unique dataset from a cyber threat intelligence platform. Analyzing more than 160 cybercrime forum conversations collected over seven months, our research reveals how cybercriminals understand AI and discuss how they can exploit its capabilities. Their exchanges reflect growing curiosity about AI’s criminal applications through legal tools and dedicated criminal tools, but also doubts and anxieties about AI’s effectiveness and its effects on their business models and operational security. The study documents attempts to misuse legitimate AI tools and develop bespoke models tailored for illicit purposes. Combining the diffusion of innovation framework with thematic analysis, the paper provides an in-depth view of emerging AI-enabled cybercrime and offers practical insights for law enforcement and policymakers.
Security researchers at Google on Tuesday released a report describing what they’re calling “Coruna,” a highly sophisticated iPhone hacking toolkit that includes five complete hacking techniques capable of bypassing all the defenses of an iPhone to silently install malware on a device when it visits a website containing the exploitation code. In total, Coruna takes advantage of 23 distinct vulnerabilities in iOS, a rare collection of hacking components that suggests it was created by a well-resourced, likely state-sponsored group of hackers.
[…]
Coruna’s code also appears to have been originally written by English-speaking coders, notes iVerify’s cofounder Rocky Cole. “It’s highly sophisticated, took millions of dollars to develop, and it bears the hallmarks of other modules that have been publicly attributed to the US government,” Cole tells WIRED. “This is the first example we’ve seen of very likely US government toolsbased on what the code is telling usspinning out of control and being used by both our adversaries and cybercriminal groups.”
TechCrunch reports that Coruna is definitely of US origin:
Two former employees of government contractor L3Harris told TechCrunch that Coruna was, at least in part, developed by the company’s hacking and surveillance tech division, Trenchant. The two former employees both had knowledge of the company’s iPhone hacking tools. Both spoke on condition of anonymity because they weren’t authorized to talk about their work for the company.
It’s always super interesting to see what malware looks like when it’s created through a professional software development process. And the TechCrunch article has some speculation as to how the US lost control of it. It seems that an employee of L3Harris’s surviellance tech division, Trenchant, sold it to the Russian government.
The 2026 US “Cyber Strategy for America” document is mostly the same thing we’ve seen out of the White House for over a decade, but with a more aggressive tone.
But one sentence stood out: “We will unleash the private sector by creating incentives to identify and disrupt adversary networks and scale our national capabilities.” This sounds like a call for hackback: giving private companies permission to conduct offensive cyber operations.
In warfare, the notion of counterattack is extremely powerful. Going after the enemy—its positions, its supply lines, its factories, its infrastructure—is an age-old military tactic. But in peacetime, we call it revenge, and consider it dangerous. Anyone accused of a crime deserves a fair trial. The accused has the right to defend himself, to face his accuser, to an attorney, and to be presumed innocent until proven guilty.
Both vigilante counterattacks, and preemptive attacks, fly in the face of these rights. They punish people before who haven’t been found guilty. It’s the same whether it’s an angry lynch mob stringing up a suspect, the MPAA disabling the computer of someone it believes made an illegal copy of a movie, or a corporate security officer launching a denial-of-service attack against someone he believes is targeting his company over the net.
In all of these cases, the attacker could be wrong. This has been true for lynch mobs, and on the internet it’s even harder to know who’s attacking you. Just because my computer looks like the source of an attack doesn’t mean that it is. And even if it is, it might be a zombie controlled by yet another computer; I might be a victim, too. The goal of a government’s legal system is justice; the goal of a vigilante is expediency.
We don’t issue letters of marque on the high seas anymore; we shouldn’t do it in cyberspace.
It’s an impressive feat, over a decade after the box was released:
Since reset glitching wasn’t possible, Gaasedelen thought some voltage glitching could do the trick. So, instead of tinkering with the system rest pin(s) the hacker targeted the momentary collapse of the CPU voltage rail. This was quite a feat, as Gaasedelen couldn’t ‘see’ into the Xbox One, so had to develop new hardware introspection tools.
Eventually, the Bliss exploit was formulated, where two precise voltage glitches were made to land in succession. One skipped the loop where the ARM Cortex memory protection was setup. Then the Memcpy operation was targeted during the header read, allowing him to jump to the attacker-controlled data.
As a hardware attack against the boot ROM in silicon, Gaasedelen says the attack in unpatchable. Thus it is a complete compromise of the console allowing for loading unsigned code at every level, including the Hypervisor and OS. Moreover, Bliss allows access to the security processor so games, firmware, and so on can be decrypted.
The collective thoughts of the interwebz
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional
Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes.The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.