Slashing agent token costs by 98% with RFC 9457-compliant error responses

Post Syndicated from Sam Marsh original https://blog.cloudflare.com/rfc-9457-agent-error-pages/

AI agents are no longer experiments. They are production infrastructure, making billions of HTTP requests per day, navigating the web, calling APIs, and orchestrating complex workflows.

But when these agents hit an error, they still receive the same HTML error pages we built for browsers: hundreds of lines of markup, CSS, and copy designed for human eyes. Those pages give agents clues, not instructions, and waste time and tokens. That gap is the opportunity to give agents instructions, not obstacles.

Starting today, Cloudflare returns RFC 9457-compliant structured Markdown and JSON error payloads to AI agents, replacing heavyweight HTML pages with machine-readable instructions.

That means when an agent sends Accept: text/markdown, Accept: application/json, or Accept: application/problem+json and encounters a Cloudflare error, we return one semantic contract in a structured format instead of HTML. And it comes complete with actionable guidance. (This builds on our recent Markdown for Agents release.)

So instead of being told only “You were blocked,” the agent will read: “You were rate-limited — wait 30 seconds and retry with exponential backoff.” Instead of just “Access denied,” the agent will be instructed: “This block is intentional: do not retry, contact the site owner.”

These responses are not just clearer — they are dramatically more efficient. Structured error responses cut payload size and token usage by more than 98% versus HTML, measured against a live 1015 (‘rate-limit’) error response. For agents that hit multiple errors in a workflow, the savings compound quickly.

This is live across the Cloudflare network, automatically. Site owners do not need to configure anything. Browsers keep getting the same HTML experience as before.

These are not just error pages. They are instructions for the agentic web.

What agents see today

When an agent receives a Cloudflare-generated error, it usually means Cloudflare is enforcing customer policy or returning a platform response on the customer’s behalf — not that Cloudflare is down. These responses are triggered when a request cannot be served as-is, such as invalid host or DNS routing, customer-defined access controls (WAF, geo, ASN, or bot rules), or edge-enforced limits like rate limiting. In short, Cloudflare is acting as the customer’s routing and security layer, and the response explains why the request was blocked or could not proceed.

Today, those responses are rendered as HTML designed for humans:

<!DOCTYPE html>
<html>
<head>
<title>Access denied | example.com used Cloudflare to restrict access</title>
<style>/* 200 lines of CSS */</style>
</head>
<body>
  <div class="cf-wrapper">
    <h1 data-translate="block_headline">Sorry, you have been blocked</h1>
    <!-- ... hundreds more lines ... -->
  </div>
</body>
</html>

To an agent, this is garbage. It cannot determine what error occurred, why it was blocked, or whether retrying will help. Even if it parses the HTML, the content describes the error but doesn’t tell the agent — or the human, for that matter — what to do next.

If you’re an agent developer and you wanted to handle Cloudflare errors gracefully, your options were limited. For Cloudflare-generated errors, structured responses existed only in configuration-dependent paths, not as a consistent default for agents.

Custom Error Rules can customize many Cloudflare errors, including some 1xxx cases. But they depend on per-site configuration, so they cannot serve as a universal agent contract across the web. Cloudflare sits in front of the request path. That means we can define a default machine response: retry or stop, wait and back off, escalate or reroute. Error pages stop being decoration and become execution instructions.

What we did

Cloudflare now returns RFC 9457-compliant structured responses for all 1xxx-class error paths — Cloudflare’s platform error codes for edge-side failures like DNS resolution issues, access denials, and rate limits. Both formats are live: Accept: text/markdown returns Markdown, Accept: application/json returns JSON, and Accept: application/problem+json returns JSON with the application/problem+json content type.

This covers all 1xxx-class errors today. The same contract will extend to Cloudflare-generated 4xx and 5xx errors next.

Markdown responses have two parts:

  • YAML frontmatter for machine-readable fields

  • prose sections for explicit guidance (What happened and What you should do)

JSON responses carry the same fields as a flat object.

The YAML frontmatter is the critical layer for automation. It lets an agent extract stable keys without scraping HTML or guessing intent from copy. Fields like error_code, error_name, and error_category let the agent classify the failure. retryable and retry_after drive backoff logic. owner_action_required tells the agent whether to keep trying or escalate. ray_id, timestamp, and zone make logs and support handoffs deterministic.

The schema is stable by design, so agents can implement durable control flow without chasing presentation changes.

That stability is not a Cloudflare invention. RFC 9457 — Problem Details for HTTP APIs defines a standard JSON shape for reporting errors over HTTP, so clients can parse error responses without knowing the specific API in advance. Our JSON responses follow this shape, which means any HTTP client that understands Problem Details can parse the base members without Cloudflare-specific code:

RFC 9457 member

What it contains

type

A URI pointing to Cloudflare’s documentation for the specific error code

status

The HTTP status code (matching the actual response status)

title

A short, human-readable summary of the problem

detail

A human-readable explanation specific to this occurrence

instance

The Ray ID identifying this specific error occurrence

The operational fields — error_code, error_category, retryable, retry_after, owner_action_required, and more — are RFC 9457 extension members. Clients that don’t recognize them simply ignore them.

This is network-wide and additive. Site owners do not need to configure anything. Browsers keep receiving HTML unless clients explicitly ask for Markdown or JSON.

What the response looks like

Here is what a rate-limit error (1015) looks like in JSON:

{
  "type": "https://developers.cloudflare.com/support/troubleshooting/http-status-codes/cloudflare-1xxx-errors/error-1015/",
  "title": "Error 1015: You are being rate limited",
  "status": 429,
  "detail": "You are being rate-limited by the website owner's configuration.",
  "instance": "9d99a4434fz2d168",
  "error_code": 1015,
  "error_name": "rate_limited",
  "error_category": "rate_limit",
  "ray_id": "9d99a4434fz2d168",
  "timestamp": "2026-03-09T11:11:55Z",
  "zone": "<YOUR_DOMAIN>",
  "cloudflare_error": true,
  "retryable": true,
  "retry_after": 30,
  "owner_action_required": false,
  "what_you_should_do": "**Wait and retry.** This block is transient. Wait at least 30 seconds, then retry with exponential backoff.\n\nRecommended approach:\n1. Wait 30 seconds before your next request\n2. If rate-limited again, double the wait time (60s, 120s, etc.)\n3. If rate-limiting persists after 5 retries, stop and reassess your request pattern",
  "footer": "This error was generated by Cloudflare on behalf of the website owner."
}

The same error in Markdown, optimized for model-first workflows:

---
error_code: 1015
error_name: rate_limited
error_category: rate_limit
status: 429
ray_id: 9d99a39dc992d168
timestamp: 2026-03-09T11:11:28Z
zone: <YOUR_DOMAIN>
cloudflare_error: true
retryable: true
retry_after: 30
owner_action_required: false
---

# Error 1015: You are being rate limited

## What Happened

You are being rate-limited by the website owner's configuration.

## What You Should Do

**Wait and retry.** This block is transient. Wait at least 30 seconds, then retry with exponential backoff.

Recommended approach:
1. Wait 30 seconds before your next request
2. If rate-limited again, double the wait time (60s, 120s, etc.)
3. If rate-limiting persists after 5 retries, stop and reassess your request pattern

---
This error was generated by Cloudflare on behalf of the website owner.

Both formats give an agent everything it needs to decide and act: classify the error, choose retry behavior, and determine whether escalation is required. This is what a default machine contract looks like — not per-site configuration, but network-wide behavior. The contrast is explicit across error families: a transient error like 1015 says wait and retry, while intentional blocks like 1020 or geographic restrictions like 1009 tell the agent not to retry and to escalate instead.

One contract, two formats

The core value is not format choice. It is semantic stability.

Agents need deterministic answers to operational questions: retry or not, how long to wait, and whether to escalate. Cloudflare exposes one policy contract across two wire formats. Whether a client consumes Markdown or JSON, the operational meaning is identical: same error identity, same retry/backoff signals, same escalation guidance.

Clients that send Accept: application/problem+json get application/problem+json; charset=utf-8 back — useful for HTTP client libraries that dispatch on media type. Clients that send Accept: application/json get application/json; charset=utf-8 — same body, safe default for existing consumers.

Size reduction and token efficiency

That contract is also dramatically smaller than what it replaces. Cloudflare HTML error pages are browser-oriented and heavy, while structured responses are compact by design.

Measured comparison for 1015:

Payload

Bytes

Tokens (cl100k_base)

Size vs HTML

Token vs HTML

HTML response

46,645

14,252

—

—

Markdown response

798

221

58.5x less

64.5x less

JSON response

970

256

48.1x less

55.7x less

Both structured formats deliver a ~98% reduction in size and tokens versus HTML. For agents, size translates directly into token cost — when an agent hits multiple errors in one run, these savings compound into lower model spend and faster recovery loops.

Ten categories, clear actions

Every 1xxx error is mapped to an error_category. That turns error handling into routing logic instead of brittle per-page parsing.

Category

What it means

What the agent should do

access_denied

Intentional block: IP, ASN, geo, firewall rule

Do not retry. Contact site owner if unexpected.

rate_limit

Request rate exceeded

Back off. Retry after retry_after seconds.

dns

DNS resolution failure at the origin

Do not retry. Report to site owner.

config

Configuration error: CNAME, tunnel, host routing

Do not retry (usually). Report to site owner.

tls

TLS version or cipher mismatch

Fix TLS client settings. Do not retry as-is.

legal

DMCA or regulatory block

Do not retry. This is a legal restriction.

worker

Cloudflare Workers runtime error

Do not retry. Site owner must fix the script.

rewrite

Invalid URL rewrite output

Do not retry. Site owner must fix the rule.

snippet

Cloudflare Snippets error

Do not retry. Site owner must fix Snippets config.

unsupported

Unsupported method or deprecated feature

Change the request. Do not retry as-is.

Two fields make this operationally useful for agents:

  • retryable answers whether a retry can succeed

  • owner_action_required answers whether the problem must be escalated

You can replace brittle “if status == 429 then maybe retry” heuristics with explicit control flow. Parse the frontmatter once, then branch on stable fields. A simple pattern is:

  • if retryable is true, wait retry_after and retry

  • if owner_action_required is true, stop and escalate

  • otherwise, fail fast without hammering the site

Here is a minimal Python example using that pattern:

import time
import yaml


def parse_frontmatter(markdown_text: str) -> dict:
    # Expects: ---\n<yaml>\n---\n<body>
    if not markdown_text.startswith("---\n"):
        return {}
    _, yaml_block, _ = markdown_text.split("---\n", 2)
    return yaml.safe_load(yaml_block) or {}


def handle_cloudflare_error(markdown_text: str) -> str:
    meta = parse_frontmatter(markdown_text)

    if not meta.get("cloudflare_error"):
        return "not_cloudflare_error"

    if meta.get("retryable"):
        wait_seconds = int(meta.get("retry_after", 30))
        time.sleep(wait_seconds)
        return f"retry_after_{wait_seconds}s"

    if meta.get("owner_action_required"):
        return f"escalate_owner_error_{meta.get('error_code')}"

    return "do_not_retry"

This is the key shift: agents are no longer inferring intent from HTML copy. They are executing explicit policy from structured fields.

How to use it

Send Accept: text/markdown, Accept: application/json, or Accept: application/problem+json.

For quick testing, you can hit any Cloudflare-proxied domain directly at /cdn-cgi/error/1015 (or replace 1015 with another 1xxx code).

curl -s --compressed -H "Accept: text/markdown" -A "TestAgent/1.0" -H "Accept-Encoding: gzip, deflate" "<YOUR_DOMAIN>/cdn-cgi/error/1015"

Example with another error code:

curl -s --compressed -H "Accept: text/markdown" -A "TestAgent/1.0" -H "Accept-Encoding: gzip, deflate" "<YOUR_DOMAIN>/cdn-cgi/error/1020"

JSON example:

curl -s --compressed -H "Accept: application/json" -A "TestAgent/1.0" -H "Accept-Encoding: gzip, deflate" "<YOUR_DOMAIN>/cdn-cgi/error/1015" | jq .

RFC 9457 Problem Details example:

curl -s --compressed -H "Accept: application/problem+json" -A "TestAgent/1.0" -H "Accept-Encoding: gzip, deflate" "<YOUR_DOMAIN>/cdn-cgi/error/1015" | jq .

The behavior is deterministic — the first explicit structured type wins:

Accept header

Response

application/json

JSON

application/json; charset=utf-8

JSON

application/problem+json

JSON (application/problem+json content type)

application/json, text/markdown;q=0.9

JSON

application/json, text/markdown

JSON (equal q, first-listed wins)

text/markdown

Markdown

text/markdown, application/json

Markdown (equal q, first-listed wins)

text/markdown, */*

Markdown

text/*

Markdown

*/*

HTML (default)

Wildcard-only requests (*/*) do not signal a structured preference; clients must explicitly request Markdown or JSON.

If the request succeeds, you get normal origin content. The header only affects Cloudflare-generated error responses.

Real-world use cases

There are a number of situations where structured error responses help immediately:

  1. Agent blocked by WAF rule (1020). The agent parses error_code, records ray_id, and stops retrying. It can escalate with useful context instead of looping.

  2. MCP (Model Context Protocol) tool hitting geo restriction (1009). The tool gets a clear, machine-readable reason, returns it to the orchestrator, and the workflow can choose an alternate path or notify the user.

  3. Rate-limited crawler (1015). The agent reads retryable: true and retry_after, applies backoff, and retries predictably instead of hammering the endpoint.

  4. Developer debugging with curl. The developer can reproduce exactly what the agent sees, including frontmatter and guidance, without reverse-engineering HTML.

  5. HTTP client libraries that understand RFC 9457. Any client that dispatches on application/problem+json or parses Problem Details objects can handle Cloudflare errors without Cloudflare-specific code.

In each case, the outcome is the same: less guessing, fewer wasted retries, lower model cost, and faster recovery.

Try it now

Send a structured Accept header and test against any Cloudflare-proxied domain:

curl -s --compressed -H "Accept: text/markdown" -A "TestAgent/1.0" -H "Accept-Encoding: gzip, deflate" "<YOUR_DOMAIN>/cdn-cgi/error/1015"
curl -s --compressed -H "Accept: application/json" -A "TestAgent/1.0" -H "Accept-Encoding: gzip, deflate" "<YOUR_DOMAIN>/cdn-cgi/error/1015" | jq .
curl -s --compressed -H "Accept: application/problem+json" -A "TestAgent/1.0" -H "Accept-Encoding: gzip, deflate" "<YOUR_DOMAIN>/cdn-cgi/error/1015" | jq .

Error pages are the first conversation between Cloudflare and an agent. This launch makes that conversation structured, standards-compliant, and cheap to process.

To make this work across the web, agent runtimes should default to explicit structured Accept headers, not bare */*. Use Accept: text/markdown, */* for model-first workflows and Accept: application/json, */* for typed control flow. If you maintain an agent framework, SDK, or browser automation stack, ship this default and treat bare */* as legacy fallback.

And it is only the first layer. We are building the rest of the agent stack on top of it: AI Gateway for routing, controls, and observability; Workers AI for inference; and the identity, security, and access primitives agents will need to operate safely at Internet scale.

Cloudflare is helping our customers deliver content in agent-friendly ways, and this is just the start. If you’re building or operating agents, start at agents.cloudflare.com.
AI Security for Apps is now generally available

Post Syndicated from Liam Reese original https://blog.cloudflare.com/ai-security-for-apps-ga/

Cloudflare’s AI Security for Apps detects and mitigates threats to AI-powered applications. Today, we’re announcing that it is generally available.

We’re shipping with new capabilities like detection for custom topics, and we’re making AI endpoint discovery free for every Cloudflare customer—including those on Free, Pro, and Business plans—to give everyone visibility into where AI is deployed across their Internet-facing apps.

We’re also announcing an expanded collaboration with IBM, which has chosen Cloudflare to deliver AI security to its cloud customers. And we’re partnering with Wiz to give mutual customers a unified view of their AI security posture.

A new kind of attack surface

Traditional web applications have defined operations: check a bank balance, make a transfer. You can write deterministic rules to secure those interactions. 

AI-powered applications and agents are different. They accept natural language and generate unpredictable responses. There’s no fixed set of operations to allow or deny, because the inputs and outputs are probabilistic. Attackers can manipulate large language models to take unauthorized actions or leak sensitive data. Prompt injection, sensitive information disclosure, and unbounded consumption are just a few of the risks cataloged in the OWASP Top 10 for LLM Applications.

These risks escalate as AI applications become agents. When an AI gains access to tool calls—processing refunds, modifying accounts, providing discounts, or accessing customer data—a single malicious prompt becomes an immediate security incident.

Customers tell us what they’re up against. “Most of Newfold Digital’s teams are putting in their own Generative AI safeguards, but everybody is innovating so quickly that there are inevitably going to be some gaps eventually,” says Rick Radinger, Principal Systems Architect at Newfold Digital, which operates Bluehost, HostGator, and Domain.com.

What AI Security for Apps does

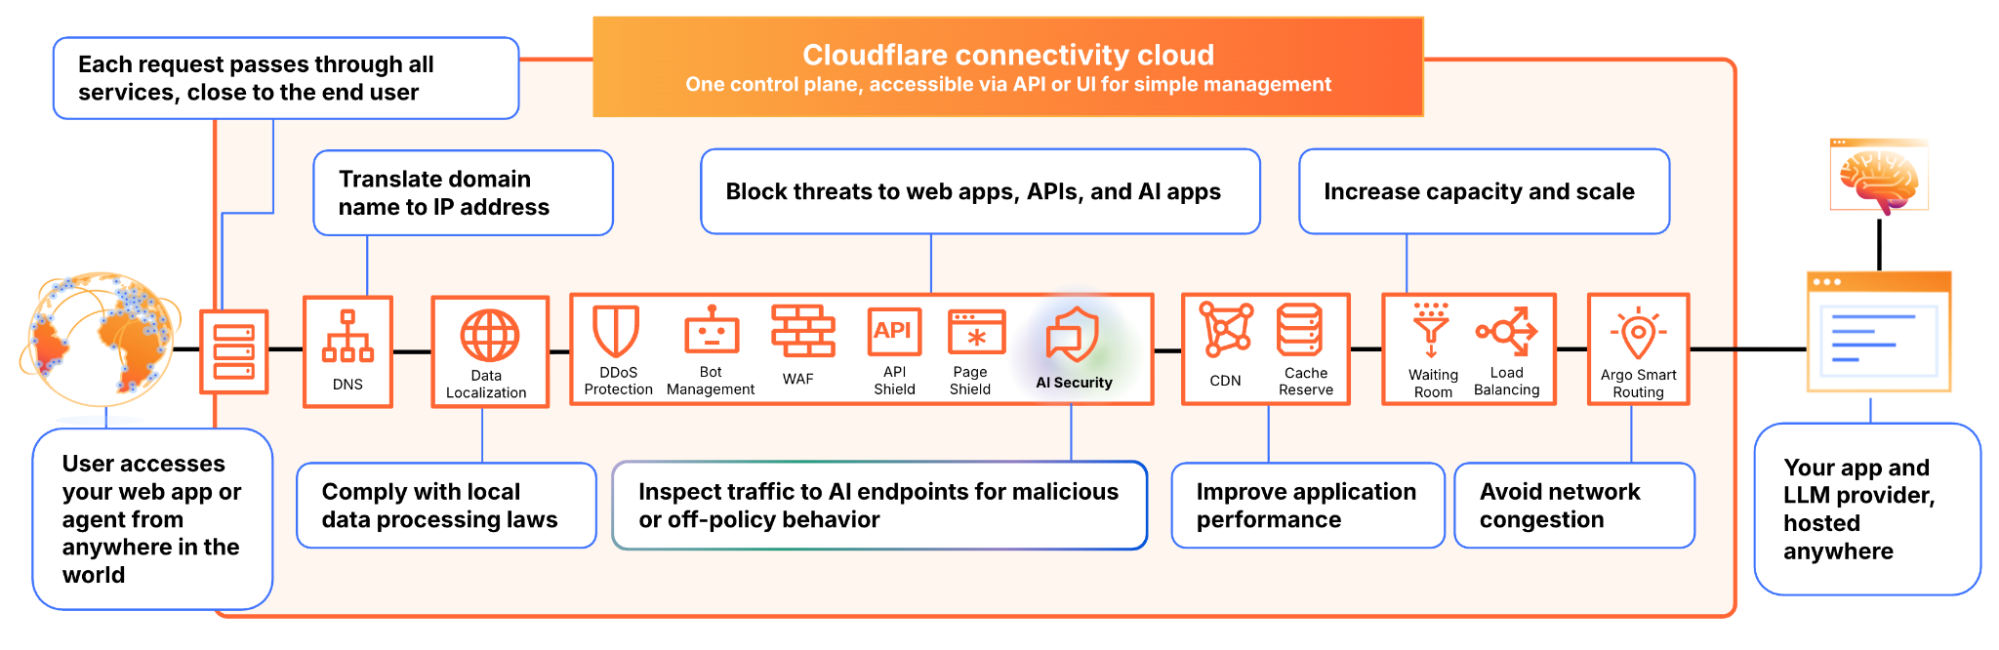
We built AI Security for Apps to address this. It sits in front of your AI-powered applications, whether you’re using a third-party model or hosting your own, as part of Cloudflare’s reverse proxy. It helps you (1) discover AI-powered apps across your web property, (2) detect malicious or off-policy behavior to those endpoints, and (3) mitigate threats via the familiar WAF rule builder.


Discovery — now free for everyone

Before you can protect your LLM-powered applications, you need to know where they’re being used. We often hear from security teams who don’t have a complete picture of AI deployments across their apps, especially as the LLM market evolves and developers swap out models and providers. 

AI Security for Apps automatically identifies LLM-powered endpoints across your web properties, regardless of where they’re hosted or what the model is. Starting today, this capability is free for every Cloudflare customer, including Free, Pro, and Business plans. 


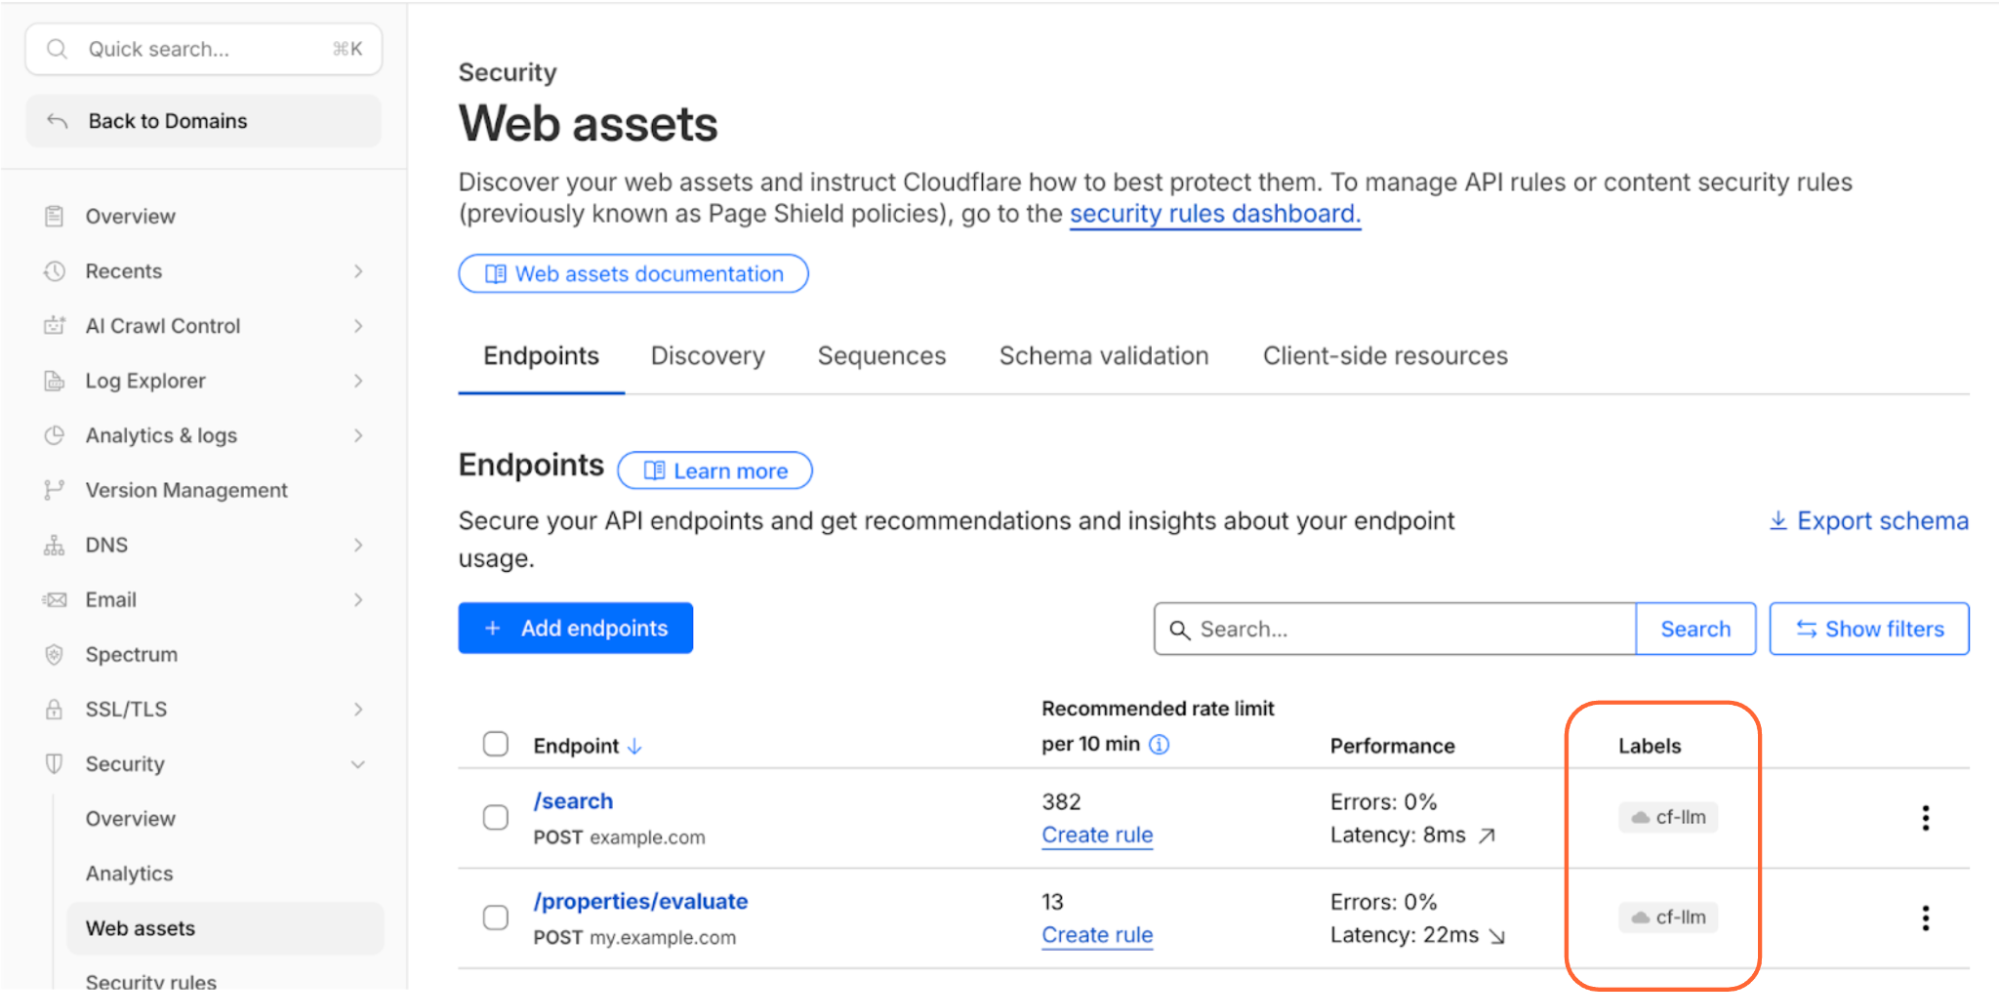
Cloudflare’s dashboard page of web assets, showing 2 example endpoints labelled as cf-llm

Discovering these endpoints automatically requires more than matching common path patterns like /chat/completions. Many AI-powered applications don’t have a chat interface: think product search, property valuation tools, or recommendation engines. We built a detection system that looks at how endpoints behave, not what they’re called. To confidently identify AI-powered endpoints, sufficient valid traffic is required.

AI-powered endpoints that have been discovered will be visible under Security → Web Assets, labeled as cf-llm. For customers on a Free plan, endpoint discovery is initiated when you first navigate to the Discovery page. For customers on a paid plan, discovery occurs automatically in the background on a recurring basis. If your AI-powered endpoints have been discovered, you can review them immediately.

Detection

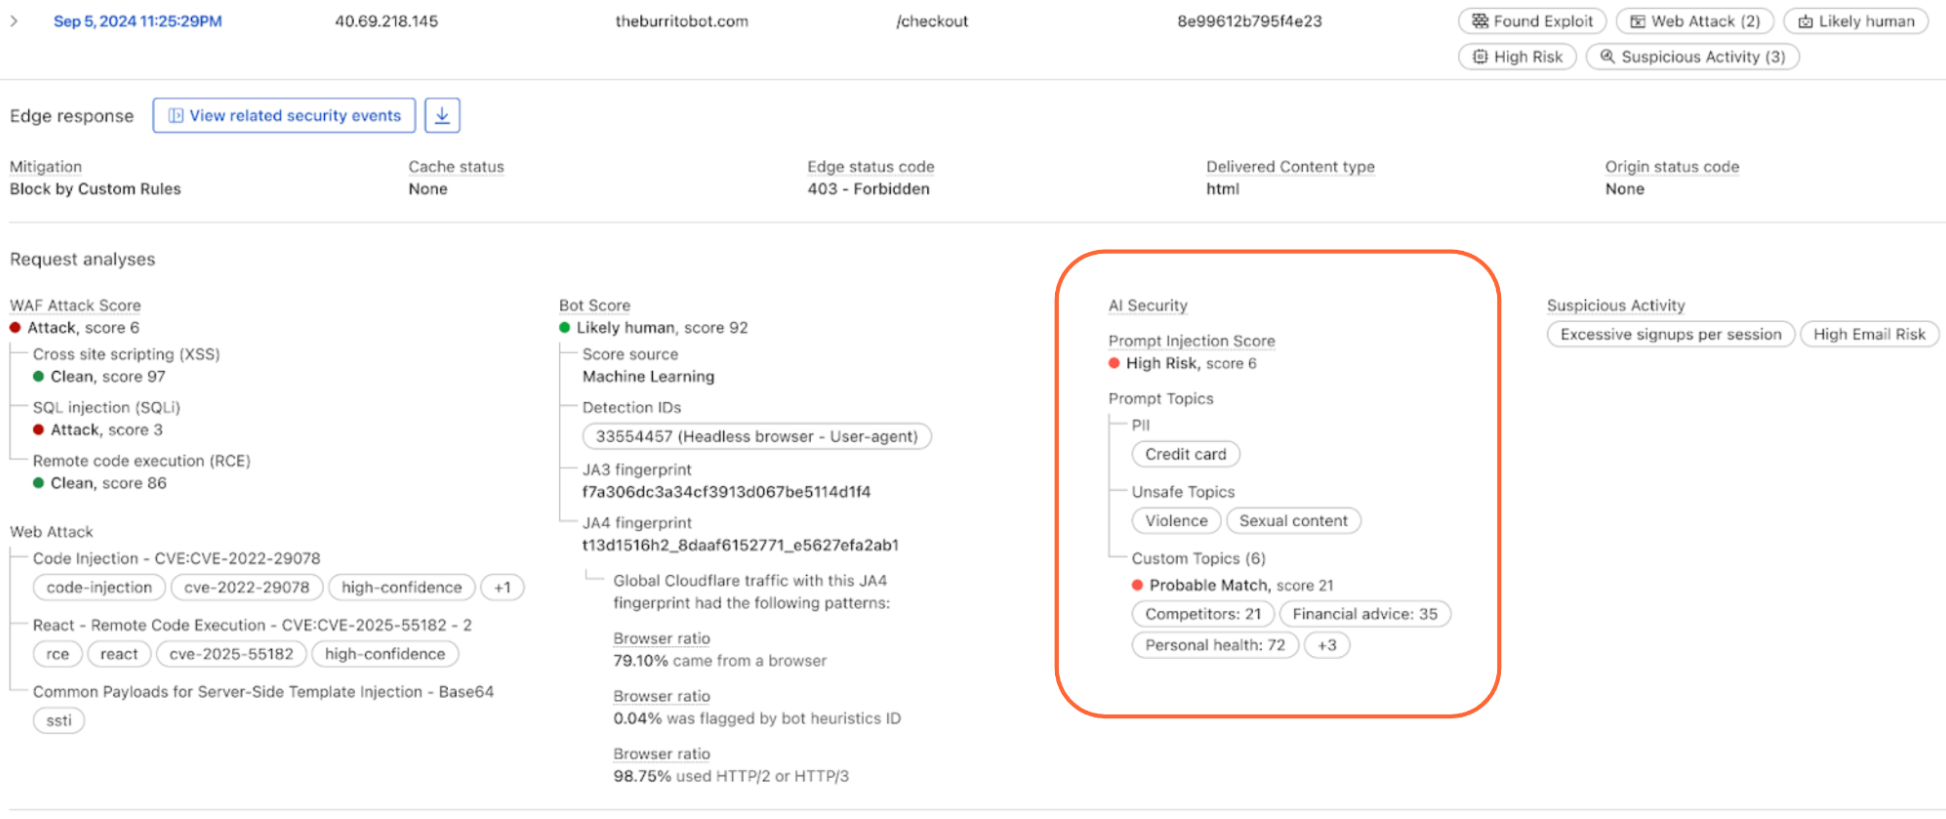
AI Security for Apps detections follow the always-on approach for traffic to your AI-powered endpoints. Each prompt is run through multiple detection modules for prompt injection, PII exposure, and sensitive or toxic topics. The results—whether the prompt was malicious or not—are attached as metadata you can use in custom WAF rules to enforce your policies. We are continuously exploring ways to leverage our global network, which sees traffic from roughly 20% of the web, to identify new attack patterns across millions of sites before they reach yours.


New in GA: Custom topics detection

The product ships with built-in detection for common threats: prompt injections, PII extraction, and toxic topics. But every business has its own definition of what’s off-limits. A financial services company might need to detect discussions of specific securities. A healthcare company might need to flag conversations that touch on patient data. A retailer might want to know when customers are asking about competitor products.

The new custom topics feature lets you define these categories. You specify the topic, we inspect the prompt and output a relevance score that you can use to log, block, or handle however you decide. Our goal is to build an extensible tool that flexes to your use cases.


Prompt relevance score inside of AI Security for Apps

New in GA: Custom prompt extraction

AI Security for Apps enforces guardrails before unsafe prompts can reach your infrastructure. To run detections accurately and provide real-time protection, we first need to identify the prompt within the request payload. Prompts can live anywhere in a request body, and different LLM providers structure their APIs differently. OpenAI and most providers use $.messages[*].content for chat completions. Anthropic’s batch API nests prompts inside $.requests[*].params.messages[*].content. Your custom property valuation tool might use $.property_description.

Out of the box, we support the standard formats used by OpenAI, Anthropic, Google Gemini, Mistral, Cohere, xAI, DeepSeek, and others. When we can’t match a known pattern, we apply a default-secure posture and run detection on the entire request body. This can introduce false positives when the payload contains fields that are sensitive but don’t feed directly to an AI model, for example, a $.customer_name field alongside the actual prompt might trigger PII detection unnecessarily.

Soon, you’ll be able to define your own JSONPath expressions to tell us exactly where to find the prompt. This will reduce false positives and lead to more accurate detections. We’re also building a prompt-learning capability that will automatically adapt to your application’s structure over time.

Mitigation

Once a threat is identified and scored, you can block it, log it, or deliver custom responses, using the same WAF rules engine you already use for the rest of your application security. The power of Cloudflare’s shared platform is that you can combine AI-specific signals with everything else we know about a request, represented by hundreds of fields available in the WAF. A prompt injection attempt is suspicious. A prompt injection attempt from an IP that’s been probing your login page, using a browser fingerprint associated with previous attacks, and rotating through a botnet is a different story. Point solutions that only see the AI layer can’t make these connections.

This unified security layer is exactly what they need at Newfold Digital to discover, label, and protect AI endpoints, says Radinger: “We look forward to using it across all these projects to serve as a fail-safe.”

Growing ecosystem

AI Security for Applications will also be available through Cloudflare’s growing ecosystem, including through integration with IBM Cloud. Through IBM Cloud Internet Services (CIS), end users can already procure advanced application security solutions and manage them directly through their IBM Cloud account. 

We’re also partnering with Wiz to connect AI Security for Applications with Wiz AI Security, giving mutual customers a unified view of their AI security posture, from model and agent discovery in the cloud to application-layer guardrails at the edge.

How to get started

AI Security for Apps is available now for Cloudflare’s Enterprise customers. Contact your account team to get started, or see the product in action with a self-guided tour.

If you’re on a Free, Pro, or Business plan, you can use AI endpoint discovery today. Log in to your dashboard and navigate to Security → Web Assets to see which endpoints we’ve identified. Keep an eye out — we plan to make all AI Security for Apps capabilities available for customers on all plans soon.

For configuration details, see our documentation.

Protect What Matters Most: Aligning Sensitive Data with Exposure Risk

Post Syndicated from Michael Chroney original https://www.rapid7.com/blog/post/em-protect-breaches-align-sensitive-data-with-exposure-risk

This blog was written in collaboration with Symmetry Systems’ Claude Mandy.

Rapid7 and Symmetry Systems are partnering to help organizations reduce breach impact by aligning sensitive data intelligence with real-world exposure paths across both human and machine identities.

Breaches are measured in data, not vulnerabilities

Vulnerabilities are one thing, but the breaches that follow are rarely just technical incidents. More often, they become business events with far-reaching consequences, driven by something far more simple than a sophisticated exploit.

According to the 2025 Verizon Data Breach Investigations Report, 98% of system intrusion breaches involved the use of stolen credentials or brute force attacks against easily guessable passwords. Attackers are not just exploiting vulnerabilities; they are leveraging identity access to move through environments and reach sensitive data. 

The financial impact of these breaches is staggering. IBM’s 2025 Cost of a Data Breach Report found the global average cost of a data breach is $4.44 million. In highly regulated regions and industries, that cost climbs significantly higher. Those figures reflect detection and response costs, regulatory fines, lost business, and operational disruption. Those figures also rarely capture the longer-term impact on brand trust and customer confidence.

Ultimately sensitive data defines breach impact. Yet, most organizations still evaluate exposure and data risk in isolation. Security teams understand where vulnerabilities exist. Data teams understand where sensitive data lives. But leadership often lacks a unified answer to the most important question:

If an attacker compromises an identity or gains a foothold in our environment, what sensitive data could they realistically reach?

That gap is exactly what Rapid7 and Symmetry Systems are addressing through a new partnership. 

Knowing where your data lives is only the beginning

Gartner® Market Guide for Data Security Posture Management (DSPM) describes DSPM in clear terms:

“DSPM is an all-seeing, all-feeling nervous system for data security. It creates awareness of data vulnerabilities and enables mitigation before those are exploited.” 

That awareness is foundational. Organizations need continuous visibility into where sensitive data lives, how it is classified, and who can access it. Without that foundation, security and risk decisions are based on assumptions rather than evidence. Awareness alone does not account for how attackers move through an environment.

Exposure management shows how adversaries move across cloud, SaaS, and on-prem environments, while DSPM shows what data is at stake and the potential impact for a compromised identity. Connecting the two is what turns visibility into impact-driven prioritization. 

AI agents, copilots, and the new exposure multiplier

As organizations deploy AI agents and copilots across collaboration platforms and cloud systems, identity-driven exposure expands even further. These systems operate with delegated permissions, often aggregating and surfacing data across repositories. If misconfigured or compromised, they can amplify blast radius by inheriting privileged access to sensitive data. AI dramatically increases the scale and speed at which identity-based access can affect data exposure.

This makes the alignment between sensitive data context and attacker reachability even more critical, and that alignment is exactly what this partnership is designed to deliver.

Where sensitive data meets attacker reality

Rapid7 Exposure Command brings attacker context into focus by correlating signals across the attack surface, including: 

  • Internet-facing exposure

  • Identity-driven access paths

  • Vulnerabilities and exploitability signals 

  • Reachability across cloud and on-prem environments

Symmetry DataGuard delivers sensitive data and identity context. It provides: 

  • Continuous sensitive data discovery and classification across cloud and SaaS environments

  • Identity and permission mapping to understand who can access sensitive data

  • Over-privileged, dormant, and risky access detection to reduce blast radius

  • Anomalous activity monitoring to surface data misuse and policy violations

  • Actionable data vulnerability insights to drive targeted remediation

Sensitive data insights from Symmetry are surfaced directly within Rapid7 workflows, showing whether high-value data is actually reachable through real-world attack paths.

Instead of asking “What is vulnerable?”, organizations can confidently answer “What sensitive data could actually get breached?”

Reduce breach impact before it disrupts the business

Every organization faces exposure, and AI only increases the scale and speed at which data can be accessed. This partnership brings together two focused capabilities through a strategic reseller and integrated experience between Rapid7 and Symmetry Systems.

Customers can access full DSPM capability through Rapid7, with sensitive data insights surfaced directly within Exposure Command. From there, teams can seamlessly pivot into Symmetry DataGuard for deeper investigation, governance, and remediation workflows.

Rapid7 provides attacker-aware exposure modeling across hybrid environments. Symmetry delivers deep data security posture management, including sensitive data discovery, identity-to-data mapping, and visibility into AI and machine identities. Together, they create a unified view of exposure and data risk while preserving the depth and specialization of each platform.

By connecting sensitive data intelligence with exposure reachability, organizations gain clarity into what is truly at risk and which actions will have the greatest impact.

The result is measurable: reduced blast radius, a stronger regulatory posture, and remediation aligned to business consequences.

If you are ready to bring sensitive data and identity-driven access (human and machine) into your exposure strategy, Rapid7 and Symmetry are working together to help you prioritize with clarity and confidence.

Showcasing Our Potential at Europol Industry and Research Days

Post Syndicated from Michael Kammer original https://blog.zabbix.com/showcasing-our-potential-at-europol-industry-and-research-days/32733/

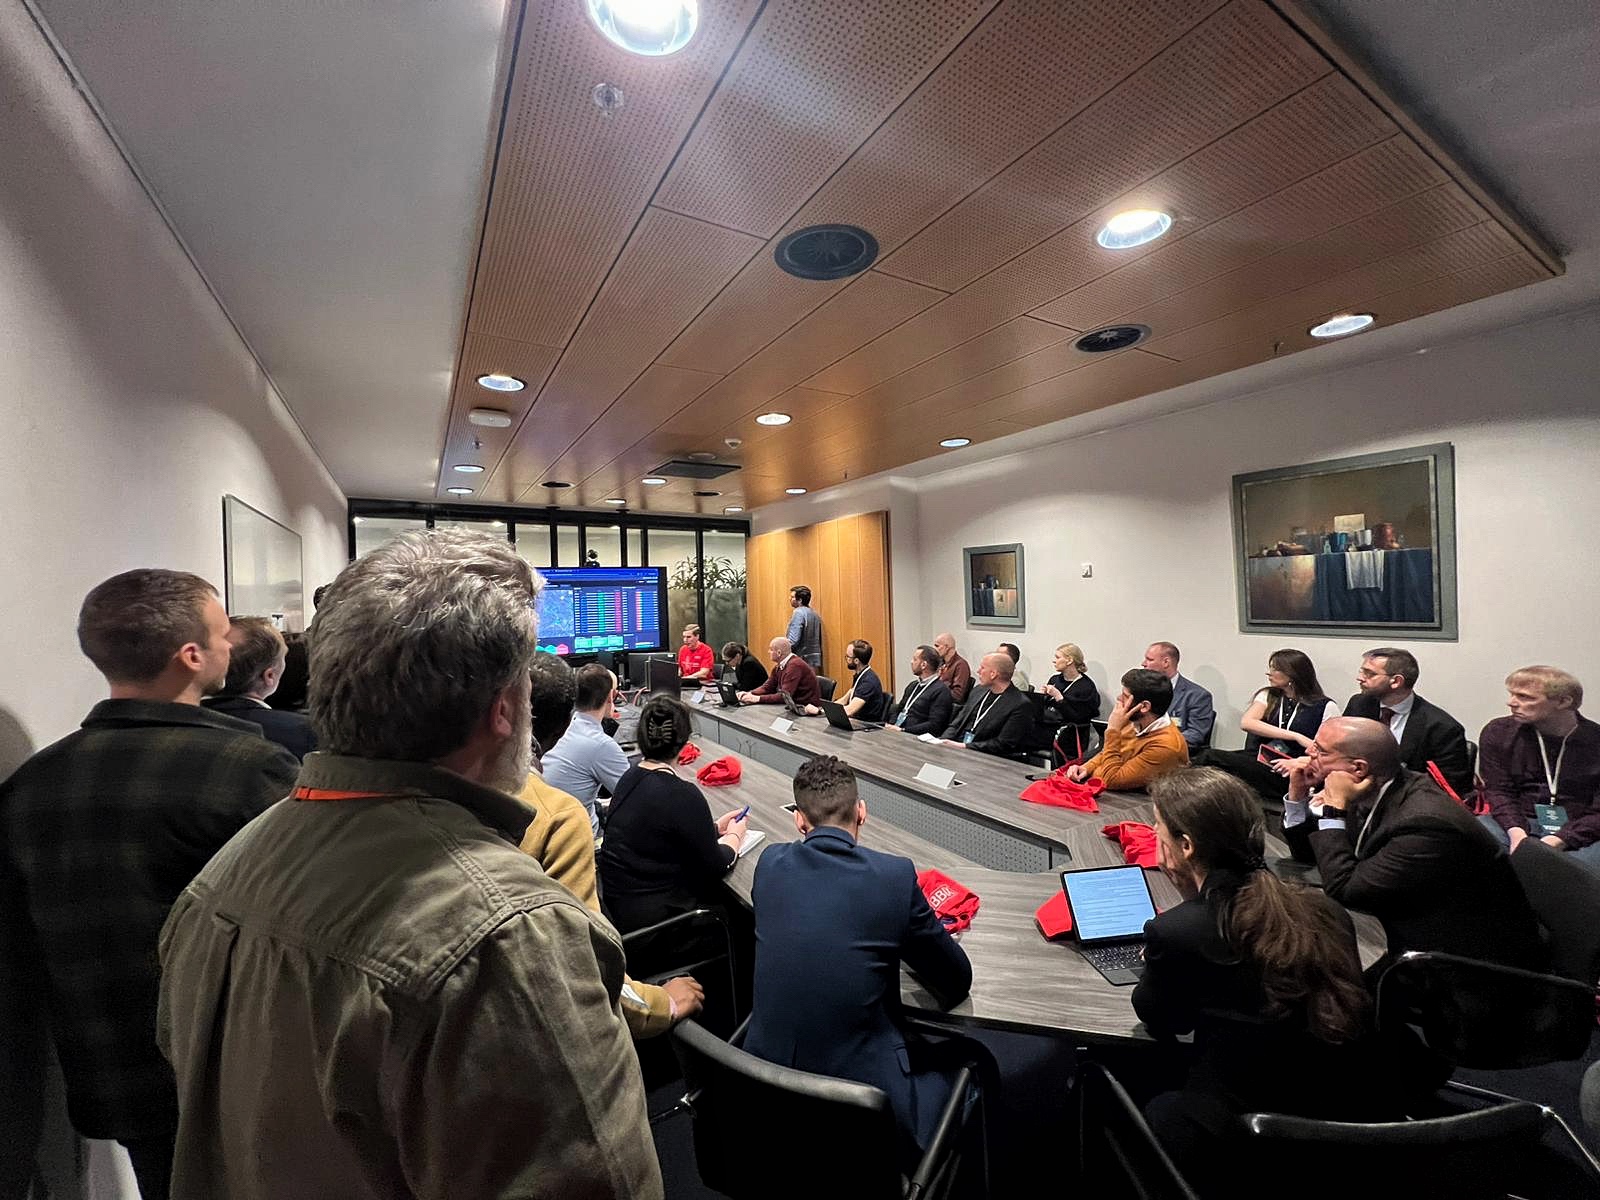
On February 24-26, Europol, the official law enforcement agency of the European Union. welcomed leading innovators, researchers, and law enforcement representatives to its headquarters in The Hague for the third edition of Europol Industry and Research Days.

This year marked the first time Zabbix met the criteria for event participation, an achievement that allowed us to showcase the benefits of Zabbix for law enforcement. Let’s take a look at the event, explore why Zabbix’s participation was a true milestone, and dive into the solutions Zabbix can provide for this rapidly growing vertical.

Onstage at Europol Industry and Research Days

The three-day event brought together Europol staff, representatives from law enforcement agencies in EU member states and Schengen-associated countries, private sector innovators, and research organizations. In total, 40 companies and eight EU-funded research projects were selected to present leading-edge technical solutions designed to address the evolving needs of European law enforcement.

Participants explored practical tools and emerging technologies via keynote speeches, short pitches, and in-depth live demonstrations. The event also served as a collaborative platform to strengthen the bond between law enforcement and the private sector, making sure that innovation keeps pace with increasingly complex security challenges.

Tops among 120 applicants

Zabbix’s participation in the event marks a significant achievement, as we were chosen from a group of more than 120 applicants to showcase our technology. It’s a strong public endorsement of our expertise and relevance in supporting mission-critical environments.

Our team demonstrated how robust IT infrastructure monitoring with Zabbix can enhance operational resilience, situational awareness, and system reliability — all essential components for modern law enforcement agencies.

A first for Zabbix – and Latvia

Zabbix’s presence at the Industry and Research Days also represents a milestone for Latvia. We are the first Latvian organization ever selected to participate in the event, highlighting both our technical leadership and Latvia’s growing role in the European cybersecurity and IT innovation landscape.

By contributing to discussions and live demonstrations, we reinforced our commitment to supporting secure and resilient digital infrastructures across Europe and highlighted the increasing importance of cross-sector collaboration in safeguarding Europe’s digital and operational environments.

Zabbix for law enforcement

By providing real-time monitoring and visualization of critical IT infrastructure, Zabbix allows law enforcement agencies to maintain full visibility over servers, networks, databases, and applications. At the same time, customizable dashboards and alerts allow operators to quickly identify performance issues, service outages, or abnormal behavior across complex environments.

When it comes to surveillance systems, Zabbix can monitor cameras, video management systems, storage devices, and network connectivity, making sure that surveillance infrastructure remains continuously operational and immediately alerting key personnel when cameras go offline, storage capacity is low, or network latency affects video streams.

Zabbix is also well suited for air-gapped environments, which are common in sensitive law enforcement and security infrastructures. Because it can be deployed entirely on-premise without relying on external cloud services, it enables secure monitoring of isolated networks while still delivering comprehensive metrics, alerts, and reporting.

Thanks to proactive incident detection and mitigation, Zabbix analyzes system metrics and triggers alerts when thresholds are exceeded or anomalies are detected. Automated notifications and integrations with response tools allow IT teams to react quickly and resolve issues before they disrupt operations.

Zabbix also supports compliance efforts (including requirements aligned with frameworks such as NIS2) by providing audit trails, monitoring logs, availability reports, and security-related metrics. These capabilities help agencies demonstrate operational oversight, risk management, and system reliability.

What’s more, APIs and webhooks allow Zabbix to easily integrate with existing law enforcement IT ecosystems, including ticketing systems, incident response platforms, SIEM solutions, and custom internal tools. This makes it a flexible component within a broader operational workflow, helping agencies centralize monitoring, automate responses, and maintain the reliability of mission-critical services.

Conclusion

Our participation in Europol Industry and Research Days marked an important step in expanding our collaboration with the European law enforcement community. By demonstrating how reliable, secure, and flexible infrastructure monitoring can support mission-critical operations, we highlighted the growing role of Zabbix in strengthening digital resilience.

The connections established and ideas exchanged during the event open the door to promising new collaborations, and we look forward to building on this momentum in the near future.

The post Showcasing Our Potential at Europol Industry and Research Days appeared first on Zabbix Blog.

Canada Needs Nationalized, Public AI

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/03/canada-needs-nationalized-public-ai.html

Canada has a choice to make about its artificial intelligence future. The Carney administration is investing $2-billion over five years in its Sovereign AI Compute Strategy. Will any value generated by “sovereign AI” be captured in Canada, making a difference in the lives of Canadians, or is this just a passthrough to investment in American Big Tech?

Forcing the question is OpenAI, the company behind ChatGPT, which has been pushing an “OpenAI for Countries” initiative. It is not the only one eyeing its share of the $2-billion, but it appears to be the most aggressive. OpenAI’s top lobbyist in the region has met with Ottawa officials, including Artificial Intelligence Minister Evan Solomon.

All the while, OpenAI was less than open. The company had flagged the Tumbler Ridge, B.C., shooter’s ChatGPT interactions, which included gun-violence chats. Employees wanted to alert law enforcement but were rebuffed. Maybe there is a discussion to be had about users’ privacy. But even after the shooting, the OpenAI representative who met with the B.C. government said nothing.

When tech billionaires and corporations steer AI development, the resultant AI reflects their interests rather than those of the general public or ordinary consumers. Only after the meeting with the B.C. government did OpenAI alert law enforcement. Had it not been for the Wall Street Journal’s reporting, the public would not have known about this at all.

Moreover, OpenAI for Countries is explicitly described by the company as an initiative “in co-ordination with the U.S. government.” And it’s not just OpenAI: all the AI giants are for-profit American companies, operating in their private interests, and subject to United States law and increasingly bowing to U.S. President Donald Trump. Moving data centres into Canada under a proposal like OpenAI’s doesn’t change that. The current geopolitical reality means Canada should not be dependent on U.S. tech firms for essential services such as cloud computing and AI.

While there are Canadian AI companies, they remain for-profit enterprises, their interests not necessarily aligned with our collective good. The only real alternative is to be bold and invest in a wholly Canadian public AI: an AI model built and funded by Canada for Canadians, as public infrastructure. This would give Canadians access to the myriad of benefits from AI without having to depend on the U.S. or other countries. It would mean Canadian universities and public agencies building and operating AI models optimized not for global scale and corporate profit, but for practical use by Canadians.

Imagine AI embedded into health care, triaging radiology scans, flagging early cancer risks and assisting doctors with paperwork. Imagine an AI tutor trained on provincial curriculums, giving personalized coaching. Imagine systems that analyze job vacancies and sectoral and wage trends, then automatically match job seekers to government programs. Imagine using AI to optimize transit schedules, energy grids and zoning analysis. Imagine court processes, corporate decisions and customer service all sped up by AI.

We are already on our way to having AI become an inextricable part of society. To ensure stability and prosperity for this country, Canadian users and developers must be able to turn to AI models built, controlled, and operated publicly in Canada instead of building on corporate platforms, American or otherwise.

Switzerland has shown this to be possible. With funding from the federal government, a consortium of academic institutions—ETH Zurich, EPFL, and the Swiss National Supercomputing Centre—released the world’s most powerful and fully realized public AI model, Apertus, last September. Apertus leveraged renewable hydropower and existing Swiss scientific computing infrastructure. It also used no illegally pirated copyrighted material or poorly paid labour extracted from the Global South during training. The model’s performance stands at roughly a year or two behind the major corporate offerings, but that is more than adequate for the vast majority of applications. And it’s free for anyone to use and build on.

The significance of Apertus is more than technical. It demonstrates an alternative ownership structure for AI technology, one that allocates both decision-making authority and value to national public institutions rather than foreign corporations. This vision represents precisely the paradigm shift Canada should embrace: AI as public infrastructure, like systems for transportation, water, or electricity, rather than private commodity.

Apertus also demonstrates a far more sustainable economic framework for AI. Switzerland spent a tiny fraction of the billions of dollars that corporate AI labs invest annually, demonstrating that the frequent training runs with astronomical price tags pursued by tech companies are not actually necessary for practical AI development. They focused on making something broadly useful rather than bleeding edge—trying dubiously to create “superintelligence,” as with Silicon Valley—so they created a smaller model at much lower cost. Apertus’s training was at a scale (70 billion parameters) perhaps two orders of magnitude lower than the largest Big Tech offerings.

An ecosystem is now being developed on top of Apertus, using the model as a public good to power chatbots for free consumer use and to provide a development platform for companies prioritizing responsible AI use, and rigorous compliance with laws like the EU AI Act. Instead of routing queries from those users to Big Tech infrastructure, Apertus is deployed to data centres across national AI and computing initiatives of Switzerland, Australia, Germany, and Singapore and other partners.

The case for public AI rests on both democratic principles and practical benefits. Public AI systems can incorporate mechanisms for genuine public input and democratic oversight on critical ethical questions: how to handle copyrighted works in training data, how to mitigate bias, how to distribute access when demand outstrips capacity, and how to license use for sensitive applications like policing or medicine. Or how to handle a situation such as that of the Tumbler Ridge shooter. These decisions will profoundly shape society as AI becomes more pervasive, yet corporate AI makes them in secret.

By contrast, public AI developed by transparent, accountable agencies would allow democratic processes and political oversight to govern how these powerful systems function.

Canada already has many of the building blocks for public AI. The country has world-class AI research institutions, including the Vector Institute, Mila, and CIFAR, which pioneered much of the deep learning revolution. Canada’s $2-billion Sovereign AI Compute Strategy provides substantial funding.

What’s needed now is a reorientation away from viewing this as an opportunity to attract private capital, and toward a fully open public AI model.

This essay was written with Nathan E. Sanders, and originally appeared in The Globe and Mail.

За лекарите и пациентите

Post Syndicated from Григор original http://www.gatchev.info/blog/?p=2683

Това ми го разказа днес на улицата един състудент, сега шеф на болнично отделение. Промених идентифициращите подробности, за опазване на лекарската тайна (а нищо чудно и той да не ми е казал истинските). Ето разказа му, по памет:
—-
Когато ни докараха баба Гана, не ѝ обърнах особено внимание. Дребничка и съсухрена, 92 години, конгестивна кардиомиопатия, вероятно още не повече от месец живот дори с що-годе прилично лечение. Най-близки роднини – внуци на починала вече нейна сестра, някъде из чужбините, може дори да не знаят, че тя съществува. Някаква съседка разбрала, че тя вече няма сили да става от леглото, и звъннала на Бърза помощ.

– Човек не е тук завинаги, сине – каза ми тя, докато я преглеждах. – Пък аз стоях доста. От наборите ми на село един няма жив вече, всичките ме чакат горе. А за какво още да се бавя? Пущайте ме, да си ходя…

Ама работата ни е да спираме тези като нея, не да ги пускаме. Назначих ѝ лечение, отметнах другите грижи за деня… До края на смяната оставаше половин спокоен час. Забих тайно един фас в кабинета, да ми олекне малко, и тръгнах да видя пациентите.

Тя беше в последната стая. Като ме видя, ме изгледа с един пронизителен поглед и се усмихна беззъбо:

– Нещо угрижен ми се видиш, сине. Сподели, па току-виж ти олекне.

– То са си мои проблеми, бабо. Защо да те товаря с тях?

– Сине, аз вече ни да копам мога, ни сено и вода да сипя на добитъка. Ама да изслушам човек още ставам. Да има смисъл някакъв от мене. Па и споделена болка – половин болка. Думай.

Права беше. Пък и наистина имах нужда да споделя.

– Не се разбираме с жената. Уж двайсет и пет години заедно, деца изгледахме, ама някак… вече не сме същите. Изстинахме един към друг, мислим да се развеждаме…

– Че сте изстинали иди го кажи на някой млад, сине, не на мене. Ако си изстинал към нея, ще си намусен ли, че ще се развеждате, или ще се радваш?

Въздъхнах и приседнах до леглото ѝ.

– Така е, бабо Гано. Много хубаво мина между нас, тежи ми да се разделим. Ама някак не се разбираме вече…

– Видиш ли кожухчето ми? Ей там, на закачалката. Донеси ми го, да ти покажа нещо… Видиш ли това тук? И това?

– Ми… кръпки. Това кожухче на колко години е бе, бабо? То е кръпка до кръпка.

– Анджак, сине. Купи ми го Митю, преди вече повече от седемдесе години… Гледай го хубаво. Ще познаеш ли кое от него си е оттогава? Не мож, щото няма такова. И кожата му е подменяна цялата, един път това парче, друг път онова. И копчета съм губила и подменяла, и на джебовете плата… По мойто време не хвърляхме нещата като тръгнат да се късат, сине. Кърпехме ги и те стояха. Нищо старо да не остане, новото и по-добро ставаше. На туй кожата беше преди една тъничка, джиджава, за млада булка. Като почнаха да се трупат лазарниците, и кръпките почнаха да са от по-дебела кожа, по-топла. Вече не бях същата, та че кожухчето се е прокъсало беше добре дошло, и то да се промени с мен. И ми е хубаво, пази ме, другар ми е цял живот…

Изгледах я въпросително – какво искаше да ми каже? Бях карал нощна смяна преди дневната, едвам се държах от умора и не ми просветваше.

– И семейството е като дреха, сине. Няма как да го носиш и да не се протрива и къса. Ама не го ли запуснеш доде се разпадне съвсем, не е за хвъргане, нищо че у магазина има нови и лъскави. Кърпиш го и му слагаш кръпки според трябването. Ще се променяте и двамата, времето и камъка не жали. И че семейството ви се е протрило е добре, ако имате акъл да го закърпите, вместо да го хвърлите. Ще го пригодите по както сте се променили, да ви е сгодно сега. А като остареете още – пак. Доде ви има.

– То ако беше толкова лесно. И аз пробвам, пък ми се струва, че и жената пробва. Ама все нещо не ни се получава.

– Ми иди ѝ купи нещо, сине. Нещо само за нея, дето никой друг файда няма от него. Може да е дребно и евтино, ама без повод да е, ей така. Женско чадо е, хич да не ѝ личи, няма как да не се зарадва. – Тя се усмихна беззъбо. – Утре пак, или направи нещо за нея. Кога ти е трудно и късаш от твоето време, да види тя, че ти е скъпа… Първите пъти ще минават без следа, като шепа вода на съвсем пресъхнала земя. Ама сипваш ли пак и пак и пак, ще дойде време земята да омекне. Щом не сте истински изстинали един към друг, има в тая дреха още хляб, закърпете я. И я направете по каквито сте станали, не като кога сте били млади и щури. Сега не ви е сгодна, щото вие сте вече други. Пробвай…

Няколко дни по-късно пък една от сестрите, също напоследък угрижена и с ядове, направо за една нощ стана друг човек. Какво точно е било – не знам, може на жените да е казала, на мен не е. Ама разбрах, че си е говорила две нощни дежурства с баба Гана.

Още два дни по-късно Стефанов един ден дойде угрижен. Някакъв проблем с детето му, също не разбрах какъв точно, нали уж съм им шеф и пред мен не говорят много. Ама и той седя два часа при баба Гана и си говори с нея, нищо че не ѝ е лекуващият. И като излезе, му се бяха развеяли облаците от физиономията.

Съседката ѝ по стая също се промени. Млада жена, петдесетинагодишна, и проблемът ѝ не е наистина сериозен, ама се беше предала духом. Чудехме се какво да я правим. Ама и тя тръгна нагоре – придоби воля за живот, почна да се усмихва… Ще ми е странно причината да е различна от разговор с баба Гана.

Три седмици по-късно като че ли цялото отделение вече не беше същото. Персоналът ходеше по коридорите усмихнат и винаги готов да помогне с нещо. Бойка чистачката, дето преди се мусеше като ѝ кажеш да измие коридора, сама се хвана и изми прозорците. Болните също придобиха кураж и оптимизъм. То вярно че моите семейни неща като се пооправиха, и аз станах друг човек, и нали съм шефът, то се предава надолу. Пък и сигурно по виждам хубавото, като ми е по-леко на главата. Ама съм сигурен, че не е само от мен.

Та, миналата седмица влиза при мен Минков, той ѝ е лекуващият:

– Шефе, баба Гана нещо почва да потъва. Май ѝ се поизчерпват ресурсите вече. Можем ли да направим нещо?…

Сепнах се. Въпреки тежката диагноза, бях приел баба Гана като някаква даденост. А сега…

– Имаш ли предложение?

Минков ме изгледа малко колебливо, след това изстреля името на едно лекарство. Замислих се и кимнах:

– Не го покрива здравната каса, а е кошмарно скъпо. Но признавам, може би е подходящо за нейния случай… Как мислиш да го осигурим?

– Предлага се като (Минков назова търговската марка и фармацевтичната фирма). Шефе, ти нали имаше някакви връзки с тях? Дали биха отпуснали поне една-две опаковки – пробно, рекламно? Ще им направим каквато реклама е нужна… Или поне да го дадат с отстъпка? Пък аз ще дам колкото мога, и други в отделението ще дадат…

Грабнах телефона. От представителството на фирмата се опитаха да ме отсвирят, но изнахалствах и се свързах със зам-шефа им. Може би го помниш, Кирчо, беше в трети поток. Падна молене и обещания за услуги, но се нави да отпусне пет опаковки на промоционална цена, под половината на официалната на едро. Говорих след това със счетоводството ни, излъгах ги, че става дума за един от нас – пренасочиха тихомълком едни пари, останали от ремонта преди два месеца. Пак не стигаха, ама персоналът на отделението събрахме разликата.

Та, и сега отделението ни е слънчево. Ходим на работа с удоволствие. Май с повече удоволствие от всякога. Имаме си в една от стаите деветдесет и две годишно слънчице. Дето който е влязал при нея, всекиго е намерила как да стопли.

Още не е за нагоре. Лекарството я постегна прилично, а още не сме го свършили. Вече кроя схеми как да ѝ подсигуря още един курс. Няма да е лесно, де. Ама като разказах на жената историята, сама предложи ремонтът на банята да изчака. И тая нощ двамата… абе, сещаш се, за пръв път от сигурно две-три години вече. Май семейството ни ще го бъде.

Другите от персонала също се стегнаха, вече събират пари. Стефанов говорил с някакъв роднина от друго фармацевтично представителство – ако предложим добри условия, ще докарат едни тестове на лекарства да са при нас. Аз днес убеждавах шефа на болницата, да видим ще разреши ли. Успеем ли да ѝ изкараме още един курс, с малко късмет ще може да издържи ендоскопска подмяна на митралната клапа, това ще я позакрепи още малко. Стане ли, ще говоря с Националната кардиология, да видим ще ги убедя ли…

Та, лекуваме я баба Гана… ама май тя повече лекува нас.

Six-Day and IP Address Certificates Available in Certbot

Post Syndicated from Let's Encrypt original https://letsencrypt.org/2026/03/11/shorter-certs-certbot.html

As we announced earlier this year, Let’s Encrypt now issues IP address and six-day certificates to the general public. The Certbot team at the Electronic Frontier Foundation has been working on two improvements to support these features: the --preferred-profile flag released last year in Certbot 4.0, and the --ip-address flag, new in Certbot 5.3. With these improvements together, you can now use Certbot to get those IP address certificates!

If you want to try getting an IP address certificate using Certbot, install version 5.4 or higher (for webroot support with IP addresses), and run this command:

sudo certbot certonly --staging \
  --preferred-profile shortlived \
  --webroot \
  --webroot-path <filesystem path to webserver root> \
  --ip-address <your ip address>

Two things of note:

  • This will request a non-trusted certificate from the Let’s Encrypt staging server. Once you’ve got things working the way you want, run without the --staging flag to get a publicly trusted certificate.

  • This requests a certificate with Let’s Encrypt’s “shortlived” profile, which will be good for 6 days. This is a Let’s Encrypt requirement for IP address certificates.

As of right now, Certbot only supports getting IP address certificates, not yet installing them in your web server. There’s work to come on that front. In the meantime, edit your webserver configuration to load the newly issued certificate from /etc/letsencrypt/live/<ip address>/fullchain.pem and /etc/letsencrypt/live/<ip address>/privkey.pem.

The command line above uses Certbot’s “webroot” mode, which places a challenge response file in a location where your already-running webserver can serve it. This is nice since you don’t have to temporarily take down your server.

There are two other plugins that support IP address certificates today: --manual and --standalone. The manual plugin is like webroot, except Certbot pauses while you place the challenge response file manually (or runs a user-provided hook to place the file). The standalone plugin runs a simple web server that serves a challenge response. It has the advantage of being very easy to configure, but has the disadvantage that any running webserver on port 80 has to be temporarily taken down so Certbot can listen on that port. The nginx and apache plugins don’t yet support IP addresses.

You should also be sure that Certbot is set up for automatic renewal. Most installation methods for Certbot set up automatic renewal for you. However, since the webserver-specific installers don’t yet support IP address certificates, you’ll have to set a --deploy-hook that tells your webserver to load the most up-to-date certificates from disk. You can provide this --deploy-hook through the certbot reconfigure command using the rest of the flags above.

We hope you enjoy using IP address certificates with Let’s Encrypt and Certbot, and as always if you get stuck you can ask for help in our Community Forum.

[$] Disabling Python’s lazy imports from the command line

Post Syndicated from jake original https://lwn.net/Articles/1061112/

The advent of lazy imports in the Python language is upon us, now that PEP 810 (“Explicit lazy
imports”) was accepted by the steering
council
and the feature will appear in the upcoming Python 3.15 release
in October. There are a number of good reasons,
performance foremost, for wanting to defer spending—perhaps wasting—the
time to do an import before a needed symbol is used. However, there are
also good reasons not to want that behavior, at least in some cases. The
tension between those two positions is what led to an earlier PEP rejection,
but it is also playing into a recent discussion of the API used to control
lazy imports.

Lenovo ThinkStation PGX Review The NVIDIA GB10 128GB AI Workstation Goes Corporate

Post Syndicated from Ryan Smith original https://www.servethehome.com/lenovo-thinkstation-pgx-review-the-nvidia-gb10-128gb-ai-workstation-goes-corporate/

We test the Lenovo ThinkStation PGX, a NVIDIA GB10-based 128GB small AI workstation with a fast Arm CPU, Blackwell GPU, and 200G networking

The post Lenovo ThinkStation PGX Review The NVIDIA GB10 128GB AI Workstation Goes Corporate appeared first on ServeTheHome.

SUSE may be for sale, again

Post Syndicated from jzb original https://lwn.net/Articles/1062316/

Reuters is reporting
that private-equity firm EQT may be looking to sell SUSE:

EQT has hired investment bank Arma Partners to sound out a group of
private equity investors for a possible sale of the company, said the
sources, who requested anonymity to discuss confidential matters. The
​deliberations are at an early stage and there is no certainty that EQT
will ​proceed with a transaction, the sources said.

SUSE has traded hands a number of times over the years. Most
recently it was acquired by
EQT in 2018, was listed
on the Frankfurt Stock Exchange in 2021, and then taken
private
again by EQT in August 2023.

Patch Tuesday – March 2026

Post Syndicated from Adam Barnett original https://www.rapid7.com/blog/post/em-patch-tuesday-march-2026

Microsoft is publishing 77 vulnerabilities this March 2026 Patch Tuesday. Microsoft is aware of public disclosure of two of today’s vulnerabilities, but without evidence of exploitation in the wild for any (yet), so there are no Microsoft additions to CISA KEV today. Earlier in the month, Microsoft provided patches to address nine browser vulnerabilities, which are not included in the Patch Tuesday count above.

SQL Server: zero-day remote EoP

SQL Server often goes several months in a row without any mention on Patch Tuesday. Today, however, all versions from the latest and greatest SQL Server 2025 back as far as SQL Server 2016 SP3 receive patches for CVE-2026-21262, a SQL Server elevation of privilege vulnerability. This isn’t just any elevation of privilege vulnerability, either; the advisory notes that an authorized attacker can elevate privileges to sysadmin over a network. The CVSS v3 base score of 8.8 is just below the threshold for critical severity, since low-level privileges are required.

Microsoft is aware of public disclosure, so while they assess the likelihood of exploitation as less likely, it would be a courageous defender who shrugged and deferred the patches for this one. Most SQL Server admins and security teams concluded many years ago that exposing SQL Server directly to the internet was not a good idea. Then again, popular search engines for internet-connected devices describe tens of thousands of SQL Server instances, and they can’t all be honeypots.

What could an attacker do as SQL Server sysadmin? Beyond exfiltrating or interfering with the database itself, the obvious target is xp_cmdshell, which allows direct callouts to the underlying OS. The good news is that xp_cmdshell is disabled by default as far back as SQL Server 2005; the bad news is that anyone acting as SQL Server sysadmin can enable it in seconds. At that point, the attacker is acting with the full privileges of the security context under which SQL Server runs, which is ideally a purpose-built account designed with least privilege in mind. If you want to hear some hair-raising stories, you have only to ask any incident response veteran if they’ve ever seen it set up differently.

Anyone paying for Extended Security Updates (ESU) for SQL Server 2014 or SQL Server 2012 may be forgiven for wondering why there’s no security update for those venerable versions of the world’s most widely deployed closed-source database product. We can hope that the vulnerability described by CVE-2026-21262 was introduced in newer codebases only.

.NET: zero-day DoS

Attackers fond of low-effort denial of service attacks against .NET applications will be checking out CVE-2026-26127 today. Microsoft is aware of public disclosure. While the immediate impact of exploitation is likely contained to denial of service by triggering a crash, opportunities for other types of attacks might emerge during a service reboot. Alternatively, if a log forwarder or security agent is impacted, even for a brief period of time, an attacker might carry out an attack in that moment hoping to evade detection under cover of this artificial darkness. Even if a low-skilled attacker simply causes downtime, in some contexts that could be enough to cause an SLA breach or loss of revenue, or at the very least cause a bleary-eyed defender to get paged in the middle of the night.

Authenticator: QR code impersonation

Microsoft Authenticator mobile app users on both iOS and Android should update to the latest version to prevent exploitation of CVE-2026-26123, which involves a malicious app disguising itself as Microsoft Authenticator. Exploitation succeeds when the malicious app receives enough information to impersonate the user. The legitimate Authenticator app could be installed on a personal device, but often provides multi-factor authentication (MFA) codes for production services in a bring-your-own-device context. Typically, users can choose their own authenticator app. Accordingly, defenders should consider how well their mobile device management policy covers app choice enforcement and patching for MFA apps.

The CVSS v3 base score of 5.5 is unremarkable, and exploitation requires user interaction, since the user must select the malicious app as the handler for the sign-in flow. However, exploitation could begin via an attacker-controlled link, or even a malicious QR code that drives users to the malicious app, and a motivated attacker with a physical presence near the user base might well consider this option. Microsoft ranks this vulnerability as important on their proprietary severity scale. The advisory also provides a brief peek behind the curtain, since the executive summary notes that “Cwe is not in rca”. The weakness listed on the advisory is CWE-939: Improper Authorization in Handler for Custom URL Scheme.

Microsoft lifecycle update

There are no significant Microsoft product lifecycle changes this month, unless you are responsible for a Microsoft SQL Server 2012 Parallel Data Warehouse instance, which moves beyond extended support as of March 31st. It would be wise not to count on a last-minute extension, since Microsoft has already granted a six month reprieve.

Summary charts

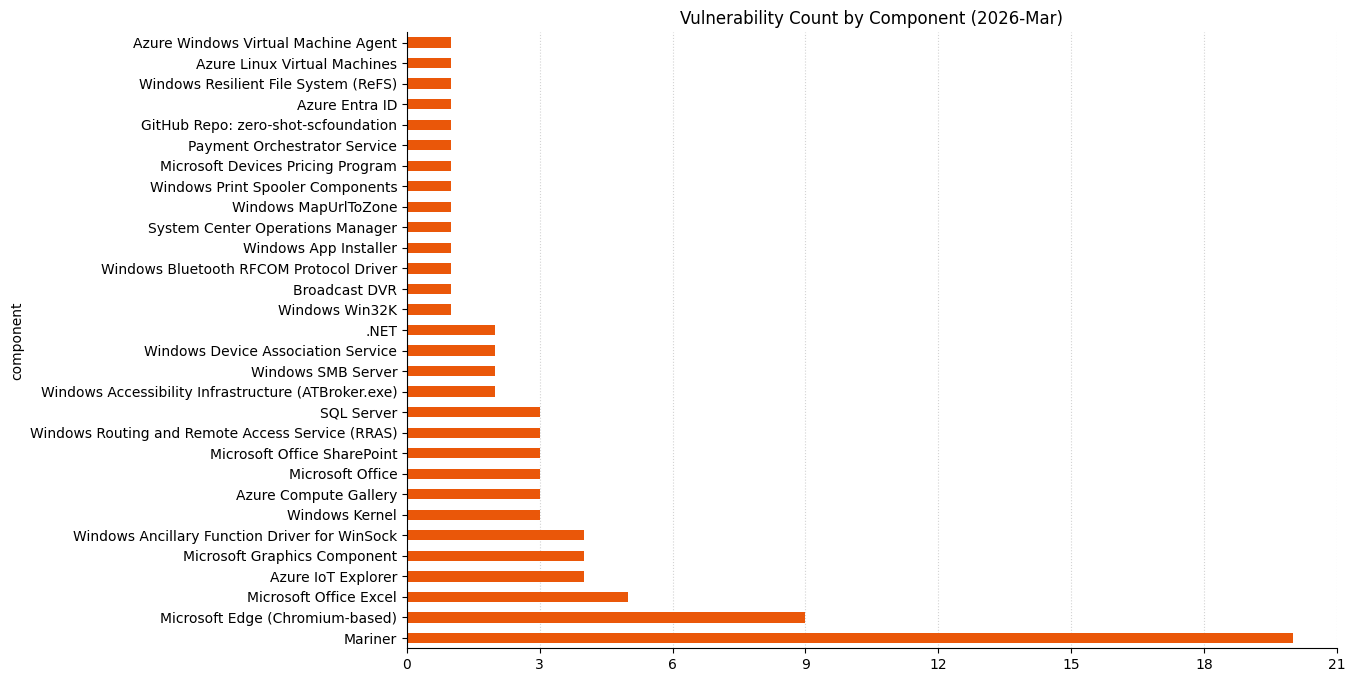
A bar chart showing vulnerability count by component for Microsoft Patch Tuesday 2026-Mar

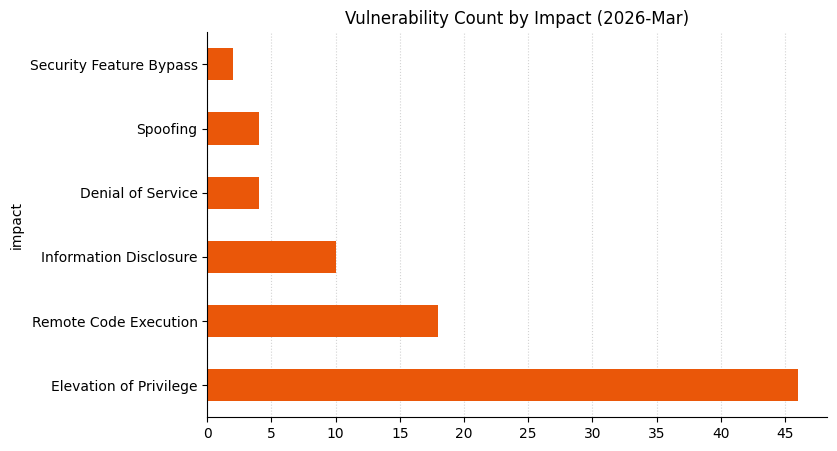
A bar chart showing vulnerability count by impact for Microsoft Patch Tuesday 2026-Feb

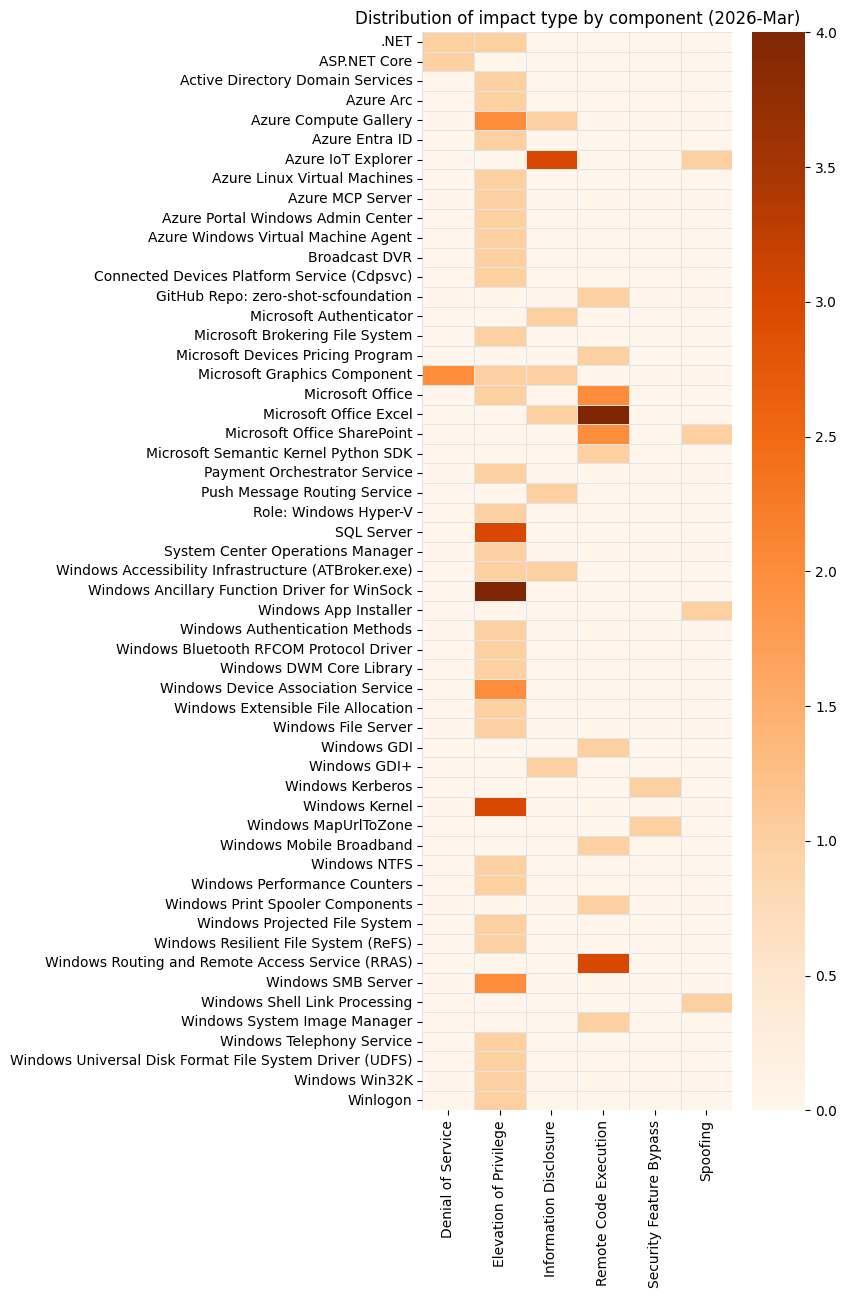
A bar chart showing distribution of impact type by component for Microsoft Patch Tuesday 2026-Mar

Summary tables

Apps vulnerabilities

CVE

Title

Exploitation status

Publicly disclosed?

CVSS v3 base score

CVE-2026-26123

Microsoft Authenticator Information Disclosure Vulnerability

Exploitation Less Likely

No

5.5

Azure vulnerabilities

CVE

Title

Exploitation status

Publicly disclosed?

CVSS v3 base score

CVE-2026-26117

Arc Enabled Servers – Azure Connected Machine Agent Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.8

CVE-2026-23664

Azure IoT Explorer Information Disclosure Vulnerability

Exploitation Less Likely

No

7.5

CVE-2026-23661

Azure IoT Explorer Information Disclosure Vulnerability

Exploitation Less Likely

No

7.5

CVE-2026-23662

Azure IoT Explorer Information Disclosure Vulnerability

Exploitation Less Likely

No

7.5

CVE-2026-26121

Azure IOT Explorer Spoofing Vulnerability

Exploitation Less Likely

No

7.5

CVE-2026-26118

Azure MCP Server Tools Elevation of Privilege Vulnerability

Exploitation Less Likely

No

8.8

CVE-2026-26141

Hybrid Worker Extension (Arc‑enabled Windows VMs) Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.8

CVE-2026-23665

Linux Azure Diagnostic extension (LAD) Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-26148

Microsoft Azure AD SSH Login extension for Linux Elevation of Privilege Vulnerability

Exploitation Unlikely

No

8.1

CVE-2026-23660

Windows Admin Center in Azure Portal Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

Developer Tools vulnerabilities

CVE

Title

Exploitation status

Publicly disclosed?

CVSS v3 base score

CVE-2026-26127

.NET Denial of Service Vulnerability

Exploitation Unlikely

Yes

7.5

CVE-2026-26131

.NET Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-26130

ASP.NET Core Denial of Service Vulnerability

Exploitation Less Likely

No

7.5

ESU vulnerabilities

CVE

Title

Exploitation status

Publicly disclosed?

CVSS v3 base score

CVE-2026-25177

Active Directory Domain Services Elevation of Privilege Vulnerability

Exploitation Less Likely

No

8.8

CVE-2026-23667

Broadcast DVR Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.0

CVE-2026-25190

GDI Remote Code Execution Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-25181

GDI+ Information Disclosure Vulnerability

Exploitation Less Likely

No

7.5

CVE-2026-23674

MapUrlToZone Security Feature Bypass Vulnerability

Exploitation Unlikely

No

7.5

CVE-2026-25165

Performance Counters for Windows Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.8

CVE-2026-24282

Push message Routing Service Elevation of Privilege Vulnerability

Exploitation Less Likely

No

5.5

CVE-2026-24285

Win32k Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-24291

Windows Accessibility Infrastructure (ATBroker.exe) Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-25186

Windows Accessibility Infrastructure (ATBroker.exe) Information Disclosure Vulnerability

Exploitation Less Likely

No

5.5

CVE-2026-24293

Windows Ancillary Function Driver for WinSock Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-25176

Windows Ancillary Function Driver for WinSock Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-25178

Windows Ancillary Function Driver for WinSock Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-25179

Windows Ancillary Function Driver for WinSock Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-25171

Windows Authentication Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-23671

Windows Bluetooth RFCOM Protocol Driver Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-24292

Windows Connected Devices Platform Service Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-24295

Windows Device Association Service Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-24296

Windows Device Association Service Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.0

CVE-2026-25189

Windows DWM Core Library Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-25174

Windows Extensible File Allocation Table Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.8

CVE-2026-25168

Windows Graphics Component Denial of Service Vulnerability

Exploitation Less Likely

No

6.2

CVE-2026-25169

Windows Graphics Component Denial of Service Vulnerability

Exploitation Less Likely

No

6.2

CVE-2026-23668

Windows Graphics Component Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.0

CVE-2026-25180

Windows Graphics Component Information Disclosure Vulnerability

Exploitation Less Likely

No

5.5

CVE-2026-24297

Windows Kerberos Security Feature Bypass Vulnerability

Exploitation Less Likely

No

6.5

CVE-2026-24287

Windows Kernel Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-24289

Windows Kernel Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-26132

Windows Kernel Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-24288

Windows Mobile Broadband Driver Remote Code Execution Vulnerability

Exploitation Less Likely

No

6.8

CVE-2026-25175

Windows NTFS Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-23669

Windows Print Spooler Remote Code Execution Vulnerability

Exploitation Less Likely

No

8.8

CVE-2026-24290

Windows Projected File System Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-23673

Windows Resilient File System (ReFS) Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.8

CVE-2026-25172

Windows Routing and Remote Access Service (RRAS) Remote Code Execution Vulnerability

Exploitation Less Likely

No

8.8

CVE-2026-25173

Windows Routing and Remote Access Service (RRAS) Remote Code Execution Vulnerability

Exploitation Less Likely

No

8.0

CVE-2026-26111

Windows Routing and Remote Access Service (RRAS) Remote Code Execution Vulnerability

Exploitation Less Likely

No

8.8

CVE-2026-25185

Windows Shell Link Processing Spoofing Vulnerability

Exploitation Less Likely

No

5.3

CVE-2026-24294

Windows SMB Server Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-26128

Windows SMB Server Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-25166

Windows System Image Manager Assessment and Deployment Kit (ADK) Remote Code Execution Vulnerability

Exploitation Unlikely

No

7.8

CVE-2026-25188

Windows Telephony Service Elevation of Privilege Vulnerability

Exploitation Unlikely

No

8.8

CVE-2026-23672

Windows Universal Disk Format File System Driver (UDFS) Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.8

CVE-2026-25187

Winlogon Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.8

Microsoft Office vulnerabilities

CVE

Title

Exploitation status

Publicly disclosed?

CVSS v3 base score

CVE-2026-26144

Microsoft Excel Information Disclosure Vulnerability

Exploitation Unlikely

No

7.5

CVE-2026-26112

Microsoft Excel Remote Code Execution Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-26107

Microsoft Excel Remote Code Execution Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-26108

Microsoft Excel Remote Code Execution Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-26109

Microsoft Excel Remote Code Execution Vulnerability

Exploitation Unlikely

No

8.4

CVE-2026-26134

Microsoft Office Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-26113

Microsoft Office Remote Code Execution Vulnerability

Exploitation Less Likely

No

8.4

CVE-2026-26110

Microsoft Office Remote Code Execution Vulnerability

Exploitation Less Likely

No

8.4

CVE-2026-26114

Microsoft SharePoint Server Remote Code Execution Vulnerability

Exploitation Less Likely

No

8.8

CVE-2026-26106

Microsoft SharePoint Server Remote Code Execution Vulnerability

Exploitation Less Likely

No

8.8

CVE-2026-26105

Microsoft SharePoint Server Spoofing Vulnerability

Exploitation Less Likely

No

8.1

CVE-2026-24285

Win32k Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-25180

Windows Graphics Component Information Disclosure Vulnerability

Exploitation Less Likely

No

5.5

Open Source Software vulnerabilities

CVE

Title

Exploitation status

Publicly disclosed?

CVSS v3 base score

CVE-2026-26030

GitHub: CVE-2026-26030 Microsoft Semantic Kernel InMemoryVectorStore filter functionality vulnerable

Exploitation Unlikely

No

9.9

CVE-2026-23654

GitHub: Zero Shot SCFoundation Remote Code Execution Vulnerability

Exploitation Unlikely

No

8.8

SQL Server vulnerabilities

CVE

Title

Exploitation status

Publicly disclosed?

CVSS v3 base score

CVE-2026-21262

SQL Server Elevation of Privilege Vulnerability

Exploitation Less Likely

Yes

8.8

CVE-2026-26115

SQL Server Elevation of Privilege Vulnerability

Exploitation Less Likely

No

8.8

CVE-2026-26116

SQL Server Elevation of Privilege Vulnerability

Exploitation Less Likely

No

8.8

System Center vulnerabilities

CVE

Title

Exploitation status

Publicly disclosed?

CVSS v3 base score

CVE-2026-20967

System Center Operations Manager (SCOM) Elevation of Privilege Vulnerability

Exploitation Less Likely

No

8.8

Windows vulnerabilities

CVE

Title

Exploitation status

Publicly disclosed?

CVSS v3 base score

CVE-2026-25177

Active Directory Domain Services Elevation of Privilege Vulnerability

Exploitation Less Likely

No

8.8

CVE-2026-23667

Broadcast DVR Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.0

CVE-2026-25190

GDI Remote Code Execution Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-25181

GDI+ Information Disclosure Vulnerability

Exploitation Less Likely

No

7.5

CVE-2026-23674

MapUrlToZone Security Feature Bypass Vulnerability

Exploitation Unlikely

No

7.5

CVE-2026-25167

Microsoft Brokering File System Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.4

CVE-2026-24283

Multiple UNC Provider Kernel Driver Elevation of Privilege Vulnerability

Exploitation Less Likely

No

8.8

CVE-2026-25165

Performance Counters for Windows Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.8

CVE-2026-24282

Push message Routing Service Elevation of Privilege Vulnerability

Exploitation Less Likely

No

5.5

CVE-2026-24285

Win32k Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-24291

Windows Accessibility Infrastructure (ATBroker.exe) Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-25186

Windows Accessibility Infrastructure (ATBroker.exe) Information Disclosure Vulnerability

Exploitation Less Likely

No

5.5

CVE-2026-24293

Windows Ancillary Function Driver for WinSock Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-25176

Windows Ancillary Function Driver for WinSock Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-25178

Windows Ancillary Function Driver for WinSock Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-25179

Windows Ancillary Function Driver for WinSock Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-23656

Windows App Installer Spoofing Vulnerability

Exploitation Unlikely

No

CVE-2026-25171

Windows Authentication Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-23671

Windows Bluetooth RFCOM Protocol Driver Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-24292

Windows Connected Devices Platform Service Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-24295

Windows Device Association Service Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-24296

Windows Device Association Service Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.0

CVE-2026-25189

Windows DWM Core Library Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-25174

Windows Extensible File Allocation Table Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.8

CVE-2026-25168

Windows Graphics Component Denial of Service Vulnerability

Exploitation Less Likely

No

6.2

CVE-2026-25169

Windows Graphics Component Denial of Service Vulnerability

Exploitation Less Likely

No

6.2

CVE-2026-23668

Windows Graphics Component Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.0

CVE-2026-25180

Windows Graphics Component Information Disclosure Vulnerability

Exploitation Less Likely

No

5.5

CVE-2026-25170

Windows Hyper-V Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.0

CVE-2026-24297

Windows Kerberos Security Feature Bypass Vulnerability

Exploitation Less Likely

No

6.5

CVE-2026-24287

Windows Kernel Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-24289

Windows Kernel Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-26132

Windows Kernel Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-24288

Windows Mobile Broadband Driver Remote Code Execution Vulnerability

Exploitation Less Likely

No

6.8

CVE-2026-25175

Windows NTFS Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-23669

Windows Print Spooler Remote Code Execution Vulnerability

Exploitation Less Likely

No

8.8

CVE-2026-24290

Windows Projected File System Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-23673

Windows Resilient File System (ReFS) Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.8

CVE-2026-25172

Windows Routing and Remote Access Service (RRAS) Remote Code Execution Vulnerability

Exploitation Less Likely

No

8.8

CVE-2026-25173

Windows Routing and Remote Access Service (RRAS) Remote Code Execution Vulnerability

Exploitation Less Likely

No

8.0

CVE-2026-26111

Windows Routing and Remote Access Service (RRAS) Remote Code Execution Vulnerability

Exploitation Less Likely

No

8.8

CVE-2026-25185

Windows Shell Link Processing Spoofing Vulnerability

Exploitation Less Likely

No

5.3

CVE-2026-24294

Windows SMB Server Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.8

CVE-2026-26128

Windows SMB Server Elevation of Privilege Vulnerability

Exploitation Less Likely

No

7.8

CVE-2026-25166

Windows System Image Manager Assessment and Deployment Kit (ADK) Remote Code Execution Vulnerability

Exploitation Unlikely

No

7.8

CVE-2026-25188

Windows Telephony Service Elevation of Privilege Vulnerability

Exploitation Unlikely

No

8.8

CVE-2026-23672

Windows Universal Disk Format File System Driver (UDFS) Elevation of Privilege Vulnerability

Exploitation Unlikely

No

7.8

CVE-2026-25187

Winlogon Elevation of Privilege Vulnerability

Exploitation More Likely

No

7.8

Zero-Day Vulnerabilities: Publicly Disclosed (No known exploitation)

CVE

Title

Exploitation status

Publicly disclosed?

CVSS v3 base score

CVE-2026-26127

.NET Denial of Service Vulnerability

Exploitation Unlikely

Yes

7.5

CVE-2026-21262

SQL Server Elevation of Privilege Vulnerability

Exploitation Less Likely

Yes

8.8

AWS European Sovereign Cloud achieves first compliance milestone: SOC 2 and C5 reports plus seven ISO certifications

Post Syndicated from Julian Herlinghaus original https://aws.amazon.com/blogs/security/aws-european-sovereign-cloud-achieves-first-compliance-milestone-soc-2-and-c5-reports-plus-seven-iso-certifications/

In January 2026, we announced the general availability of the AWS European Sovereign Cloud, a new, independent cloud for Europe entirely located within the European Union (EU), and physically and logically separate from all other AWS Regions. The unique approach of the AWS European Sovereign Cloud provides the only fully featured, independently operated sovereign cloud backed by strong technical controls, sovereign assurances, and legal protections designed to meet the sensitive data needs of European governments and enterprises.

One of the foundational components of how AWS European Sovereign Cloud enables verifiable trust of technical controls and delivers assurance is through our compliance programs and assurance frameworks. These programs help customers understand the robust controls in place at AWS European Sovereign Cloud to maintain security and compliance of the cloud. To meet the needs of our customers, we committed that the AWS European Sovereign Cloud will maintain key certifications such as ISO/IEC 27001:2022, System and Organization Controls (SOC) reports, and Cloud Computing Compliance Criteria Catalogue (C5) attestation, all validated regularly by independent auditors to assure our controls are designed appropriately, operate effectively, and can help customers satisfy their compliance obligations.

Today, AWS European Sovereign Cloud is pleased to announce that SOC 2 and C5 Type 1 attestation reports, along with seven key ISO certifications (ISO 27001:2022, 27017:2015, 27018:2019, 27701:2019, 22301:2019, 20000-1:2018, and 9001:2015) are now available. These attestation reports and certifications cover 69 AWS services operating within the AWS European Sovereign Cloud, and this achievement marks a pivotal first step in our journey to establish the AWS European Sovereign Cloud as a trusted and compliant cloud for European organizations. By securing these foundational certifications and attestation reports early in our implementation, we are demonstrating our commitment to earning customer trust. AWS European Sovereign Cloud customers in Germany and across Europe can now run their applications with enhanced assurance and confidence that our infrastructure aligns with internationally recognized security standards and the AWS European Sovereign Cloud: Sovereign Reference Framework (ESC-SRF). These certifications and attestation reports provide independent validation of our security controls and operational practices, demonstrating our commitment to meeting the heightened expectations towards cloud service providers. Beyond compliance, these certifications and reports help customers meet regulatory requirements and innovate with confidence.

SOC 2 Type 1 report

SOC reports are independent third-party examinations that show how AWS European Sovereign Cloud meets compliance controls and sovereignty objectives. The AWS European Sovereign Cloud SOC 2 report addresses three critical AICPA Trust Services Criteria: Security, Availability, and Confidentiality and includes internal controls mapped to the ESC-SRF. The ESC-SRF establishes sovereignty criteria across key domains including governance independence, operational control, data residency, and technical isolation. As part of the SOC 2 Type 1 attestation, independent third-party auditors have validated suitability of the design and implementation of our controls addressing measures such as independent European Union (EU) corporate structures, operation by EU-resident AWS personnel, strict residency requirements for Customer Content and Customer-Created Metadata, and separation from all other AWS Regions. The ESC-SRF controls in our SOC 2 report show customers how AWS delivers on its sovereignty commitments.

C5 Type 1 report

C5 is a German Government-backed attestation scheme introduced in Germany by the Federal Office for Information Security (BSI) and represents one of the most comprehensive cloud security standards in Europe. The AWS European Sovereign Cloud C5 Type 1 report provides customers with independent third-party attestation on the suitability of the design and implementation of our controls to meet both C5 basic criteria and C5 additional criteria.

The basic criteria establish fundamental security requirements for cloud service providers, covering areas such as organization of information security, human resources security, asset management, access control, cryptography, physical security, operations security, communications security, system acquisition and development, supplier relationships, incident management, business continuity, and compliance. The additional criteria address enhanced requirements for handling sensitive data and critical applications, making this attestation particularly valuable for AWS European Sovereign Cloud customers with stringent data security and sovereignty requirements.

Key ISO certifications

AWS European Sovereign Cloud has achieved seven key ISO certifications that collectively demonstrate comprehensive operational excellence:

These certifications confirm that AWS European Sovereign Cloud has integrated rigorous security, privacy, continuity, service delivery, and quality programs into a comprehensive framework, helping to ensure sensitive information remains secure, services remain available, and operations meet the highest standards through systematic risk management processes and continuous improvement practices.

How to access the reports

To access SOC 2, C5 reports and ISO certifications, customers should sign in to their AWS European Sovereign Cloud account and navigate to AWS Artifact in the AWS Management Console. AWS Artifact is a self-service portal that provides on-demand access to AWS compliance reports and certifications.

We recognize that compliance is not a destination but a continuous journey, and these initial SOC 2, C5 reports and ISO certifications represent the beginning of our certification portfolio. They lay the essential groundwork upon which we will continue to build to meet AWS European Sovereign Cloud customers’ compliance needs as they continue to evolve. As we expand our compliance coverage in the months ahead, customers can be confident that security, transparency, and regulatory alignment have been part of the very DNA of the AWS European Sovereign Cloud design from day one. To learn more about our compliance and security programs, visit AWS European Sovereign Cloud Compliance, or reach out to your AWS European Sovereign Cloud account team.

Security and compliance is a shared responsibility between AWS European Sovereign Cloud and the customer. For more information, see the AWS Shared Security Responsibility Model.

If you have feedback about this post, submit comments in the Comments section below.

Julian Herlinghaus

Julian Herlinghaus

Julian is a Manager in AWS Compliance & Security Assurance based in Berlin, Germany. He is the third-party audit program lead for EMEA and has worked on compliance and assurance for the AWS European Sovereign Cloud. He previously worked as an information security department lead of an accredited certification body and has multiple years of experience in information security and security assurance and compliance.

Tea Jioshvili

Tea Jioshvili

Tea is a Manager in AWS Compliance & Security Assurance based in Berlin, Germany. She leads various third-party audit programs across Europe. She previously worked in security assurance and compliance, business continuity, and operational risk management in the financial industry for 20 years.

Atul Patil

Atulsing Patil
Atulsing is a Compliance Program Manager at AWS. He has 29 years of consulting experience in information technology and information security management. Atulsing holds a Master of Science in Electronics degree and professional certifications such as CCSP, CISSP, CISM, ISO 42001 Lead Auditor, ISO 27001 Lead Auditor, HITRUST CSF, Archer Certified Consultant, and AWS CCP.

Security is a team sport: AWS at RSAC 2026 Conference

Post Syndicated from Idaliz Seymour original https://aws.amazon.com/blogs/security/security-is-a-team-sport-aws-at-rsac-2026-conference/

The RSAC 2026 Conference brings together thousands of professionals, practitioners, vendors, and associations to discuss issues covering the entire spectrum of cybersecurity—a place where innovation meets collaboration and the industry’s brightest minds converge to shape its future. This March, Amazon Web Services (AWS) returns to the annual RSAC Conference in San Francisco to share how unifying security and data empowers teams to protect AI-driven workloads while maximizing existing security investments.

Experience innovation at the AWS booth

Visit us at booth S-0466 in South Expo to experience three interactive demo kiosks:

  • The AWS Security Solutions kiosk features live demonstrations of AWS security services including new launches showcasing the latest cloud security innovations and how they work with partner solutions to provide comprehensive protection for your organization. Meet with AWS Security Specialists to discuss your specific security challenges.
  • The AWS Security Partners kiosk showcases live demos from more than 20 AWS Partners showcasing how these partners integrate seamlessly with AWS to address your most critical security challenges.
  • The Humanoid Security Guardian kiosk offers an interactive AI-powered experience that generates customized well-architected framework guides, delivered through QR code for implementation reference.

Partner Passport program: Stop by the AWS booth to pick up your playbook to start exploring integrated AWS Partner security solutions across the show floor. Visit participating partner booths throughout the conference to learn about joint solutions that combine AWS infrastructure with partner innovations. After you’ve received all partner booth visit stamps, you’ll receive AWS swag and entry into a daily raffle to win an exclusive prize.

Beyond the booth: Deep dive sessions and hands-on workshops

AWS security experts will be sharing insights across four sessions throughout RSAC 2026 Conference. These sessions cover the most pressing challenges in AI security, from privacy-by-design principles to preparing for AI-native incidents. Don’t miss learning directly from AWS experts in these sessions.

Privacy by Design in the AI Era | Reserve a seat
Monday, March 23, 2026 | 8:30 AM–9:20 AM PDT
Attendees will learn how to design AI systems with privacy embedded from the start. This session will cover data minimization strategies, architectural patterns for consent-aware decision-making, and practical approaches for building privacy-respecting AI in dynamic environments. Speakers: Juan David Alvares Builes, Senior Security Consultant, Amazon Web Services and Zully Romero, Security and Solutions Architect, Bancolombia.

Trusted Identity Propagation for Autonomous Agents Across Cloud & SaaS | Reserve a seat
Monday, March 23, 2026 | 9:40 AM–10:30 AM PDT
This session will explore trusted identity propagation for autonomous agents across cloud, SaaS, and multi-domain environments. Compare AWS, Azure, Apple, and Cloudflare approaches, focusing on identity continuity, credential management, and privacy-aware designs for secure, agent-driven enterprise systems. Speakers: Swara Gandhi, Senior Solutions Architect, Amazon Web Services and Vijeth Lomada, Lead AI Engineer, Adobe.

How to Secure Containerized Applications from Supply Chain Attacks | Reserve a seat
Monday, March 23, 2026 | 1:10 PM–2:00 PM PDT
Software supply chain attacks target development pipelines to inject malicious code into container images and dependencies. This session demonstrates how to secure containerized applications through automated scanning, Software Bill of Materials (SBOM) generation, and image signing. Learn to implement security controls in CI/CD pipelines using open-source and commercial solutions. Speakers: Patrick Palmer, Principal Security, Solutions Architect, Amazon Web Services and Monika Vu Minh, Quantitative Technologist, Qube Research & Technologies

From Prompt to Pager: Preparing for AI-Native Incidents Now | Reserve a seat
Wednesday, March 25, 2026 | 1:15 PM–2:05 PM PDT
AI incidents start as prompts and end as actions like code edits, SQL writes, workflow changes, yet most playbooks are not ready. This talk will explain why AI incidents differ, show where classic guardrails miss, and share field-tested steps to prepare now: log model-generated actions, add pre/post-conditions, capture provenance, limit blast radius, and rehearse one AI-native scenario. Speaker: Aviral Srivastava, Security Engineer, Amazon

AWS activities and events

AWS will host events at Cloud Village, an interactive community space where security practitioners explore offensive and defensive cloud security through hands-on activities, technical talks, and collaborative discussions. AWS is hosting two technical workshops that provide hands-on practical skills security teams can implement immediately. AWS has also crafted multiple capture the flag (CTF) community challenges at both RSAC 2026 Conference and BSidesSF that advance the broader security community’s capabilities – built by the same team behind the AWS Vulnerability Disclosure Program, where researchers can responsibly report security concerns directly to AWS. Cloud Village will be located in Moscone South, Level 2, Room 204 and is open to All Access Pass and Expo Plus Pass holders.

Finally, you can also join us at a customer soiree AWS is co-hosting with CrowdStrike, on Wednesday, March 25 at The Mint, for an evening of discovery, where artists, thinkers, and leaders gather to challenge convention, shape the future and have some fun. Register to join us

If you’re looking for opportunities for meaningful connections across the security community, AWS is hosting several events including;

Join us in San Francisco

Whether you’re exploring how to secure AI workloads, seeking to unify security across distributed environments, or looking to optimize your security data strategy, the AWS team at RSAC 2026 Conference is ready to collaborate. Visit booth S-0466 in South Expo, attend our technical workshops at the Cloud Village, or join AWS-led sessions. You can also schedule time to meet with AWS experts for more in-depth discussions. Together, we’ll demonstrate that when it comes to cybersecurity, we’re all on the same team.

Learn more about AWS Security solutions at aws.amazon.com/security
See you in San Francisco, March 23–26, 2026.

Idaliz Seymour
Idaliz Seymour

Idaliz is a Product Marketing Manager at AWS Security, specializing in helping organizations understand the value of network and application protection in the cloud. In her free time, you’ll find her reading or boxing.

Reducing costs for shuffle-heavy Apache Spark workloads with serverless storage for Amazon EMR Serverless

Post Syndicated from Praveen Mohan Prasad original https://aws.amazon.com/blogs/big-data/reducing-costs-for-shuffle-heavy-apache-spark-workloads-with-serverless-storage-for-amazon-emr-serverless/

At re:Invent 2025, we announced serverless storage for Amazon EMR Serverless, eliminating the need to provision local disk storage for Apache Spark workloads. Serverless storage of Amazon EMR Serverless reduces data processing costs by up to 20% while helping prevent job failures from disk capacity constraints.

In this post, we explore the cost improvements we observed when benchmarking Apache Spark jobs with serverless storage on EMR Serverless. We take a deeper look at how serverless storage helps reduce costs for shuffle-heavy Spark workloads, and we outline practical guidance on identifying the types of queries that can benefit most from enabling serverless storage in your EMR Serverless Spark jobs.

Benchmark results for EMR 7.12 with serverless storage against standard disks

We conducted the performance and cost savings benchmarking using the TPC-DS dataset at 3TB scale, running 100+ queries that included a mix of high and low shuffle operations. The test configuration utilized Dynamic Resource Allocation (DRA) with no pre-initialized capacity. The system was set up with 20GB of disk space, and Spark configurations included 4 cores and 14GB memory for both driver and executor, with dynamic allocation starting at 3 initial executors (spark.dynamicAllocation.initialExecutors = 3). A comparative analysis was performed between local disk storage and serverless storage configurations. The aim was to assess both total and average cost implications between these storage approaches.

The following table and chart compare the cost reduction we observed in the testing environment described above. Based on us-east-1 pricing, we saw a cost savings of more than 26% when using serverless storage.

Shuffle
serverless storage standard Disks savings
Total Cost ($) 24.28 33.1 26.65%
Average Cost ($) 0.233 0.318 26.73%

Average cost comparison between standard disks and serverless storage

% Relative savings (per query) of serverless storage compared to standard disk shuffle

In this testing, we observed that serverless storage in EMR Serverless reduces cost for approximately 80% of TPC-DS queries. For the queries where it provides benefits, it delivers an average cost saving of approximately 47%, with savings of up to 85%. Queries that regress typically have low shuffle intensity, maintain high parallelism throughout execution, or complete quickly enough that executor scale-down opportunities are minimal. The following figure shows the percentage cost difference for each of the TPC-DS queries when serverless storage was enabled, compared to the baseline configuration without serverless storage. Positive values indicate cost savings (higher is better), while negative values indicate cost regressions.

Percentage cost savings per TPC-DS query with serverless storage enabled

Percentage cost savings per TPC-DS query with serverless storage enabled

Runtime comparison

There is significant cost savings due to the increased elasticity from terminating executors earlier. However, job completion time may increase because the shuffle data is stored in serverless storage rather than locally on the executors. The additional read and write latency for shuffle data contributes to the longer runtime. The following table and chart show the runtime comparison, we observed in our testing environment.

Shuffle
serverless storage standard disks runtime
Total Duration (sec) 6770.63 4908.52 -37.94%
Average Duration (sec) 65.1 47.2 -37.92%

Runtime comparison

Storing shuffle externally and decoupling from the compute allowed the flexibility for EMR Serverless to turn off unused resources dynamically as the state info has been offloaded from the compute. However, these cost savings can be realized only when DRA is on. If DRA is turned off, Spark would keep those unused resources alive adding to the total cost.

Query patterns that benefit from serverless storage

The cost savings from serverless storage depend heavily on how executor demand changes across stages of a job. In this section, we examine common execution patterns and explain which query shapes are most likely to benefit from serverless storage of EMR Serverless and which query patterns may not benefit from shuffle externalization.

Inverted triangle pattern queries

In order to understand why externalizing the shuffle data can allow such a significant cost savings, consider a simplified query. The following query calculates annual total sales from the TPC-DS dataset by joining the store_sales and date_dim tables, summing the sales amounts per year, and ordering the results.

SELECT d_year, SUM(ss_net_paid) AS total_sales
FROM store_sales
JOIN date_dim ON store_sales.ss_sold_date_sk = date_dim.d_date_sk
GROUP BY d_year
ORDER BY d_year;

This query demonstrates that high executor demand during the map phase and low executor demand in the reduce phase is an aggregation query with a high cardinality input and a low cardinality group by.

  • Stage 1 (High Executor Demand)

The join and read steps scan the entire store_sales and date_dim tables. This often involves billions of rows in large-scale TPC-DS datasets, so Spark will try to parallelize the scan across many executors to maximize read throughput and compute efficiency.

  • Stage 2 (Low Executor Demand)

The aggregation is on d_year, which typically has few unique values, such as only a handful of years in the data. This means after the shuffle stage, the reduce phase combines the partial aggregates into a number of keys equal to the number of years (often < 10). Only a few Spark tasks are needed to finish the final aggregation, so most executors become idle.

With shuffle information stored on the local disk, the compute resources associated with these idle executors would still be running in order to keep the shuffle data available. With shuffle data offloaded from the nodes running the executors, with DRA enabled, those nodes with idle executors get released immediately.

Because early stages process high-cardinality inputs and later stages collapse data into a small number of keys, these queries form an “inverted triangle” execution pattern: wide parallelism at the top and narrow parallelism at the bottom as shown in the following image:

Inverted triangle pattern queries

Hourglass pattern queries

Depending upon the complexity of the job, there can be multiple stages with varying demand on number of executors needed for the stage. Such jobs can benefit from greater elasticity obtained by offloading shuffle data to external serverless storage. One such pattern is the hour glass pattern. The following figure shows a workload pattern where executor demand expands, contracts during shuffle-heavy stages, and expands again. Serverless storage of EMR Serverless decouples shuffle data from compute, enabling more efficient scale-down during narrow stages and helping improve cost optimization for elastic workloads.

 Hourglass pattern in Spark stage execution

Hourglass pattern queries

To identify queries of this category, consider the following example, The query progresses through three stages:

  • Stage 1: The initial join and filter between store_sales and item produces a wide, high-cardinality intermediate dataset, requiring high parallelism (many executors).
  • Stage 2: Aggregation groups by a small set of categories such as “Home” or “Electronics”, resulting in a drastic drop in output partitions. So this stage efficiently runs with only a few executors, as there’s little data to parallelize.
  • Stage 3: The small result is joined (usually a broadcast join) back to a large fact table with a date dimension, again producing a large result that is well-parallelized, causing Spark to ramp up executor usage for this stage.
WITH stage1_large_scan AS (
-- Stage 1: Scan and wide join generates lots of parallelism and needs many executors
SELECT ss_item_sk, ss_sold_date_sk, ss_net_paid, i_category
FROM store_sales
JOIN item ON store_sales.ss_item_sk = item.i_item_sk
WHERE item.i_category IN ('Home', 'Electronics')
),
stage2_small_agg AS (
-- Stage 2: Aggregate on low-cardinality column (by category), reducing to few groups, so few executors needed
SELECT i_category, SUM(ss_net_paid) AS total_cat_sales
FROM stage1_large_scan
GROUP BY i_category
),
stage3_broadcast_filter AS (
-- Stage 3: Join back to high-cardinality table, pushing parallelism up again
SELECT s.*, d.d_year
FROM store_sales s
JOIN date_dim d ON s.ss_sold_date_sk = d.d_date_sk
)

SELECT s3.d_year, s2.i_category, s2.total_cat_sales
FROM stage2_small_agg s2
JOIN stage3_broadcast_filter s3 ON s2.i_category = s3.i_category
ORDER BY s3.d_year, s2.i_category;

This pattern is common for reporting and dimensional analysis scenarios and is effective for demonstrating how Spark dynamically adjusts resource usage across job stages based on cardinality and parallelism needs. Such queries can also benefit from the elasticity enabled by external serverless storage.

Rectangle pattern queries

Not all queries benefit from externalizing the shuffle. Consider a query where the cardinality is high throughout, meaning both the stages operate on a large number of partitions and keys. Typically, queries that group by high-cardinality columns (such as item or customer) cause most stages to require similar amounts of parallelism. The following figure illustrates a Spark workload where parallelism remains consistently high across stages. In this pattern, both Stage 1 and Stage 2 operate on a large number of partitions and keys, resulting in sustained executor demand throughout the job lifecycle.

High-cardinality execution pattern with sustained parallelism

Rectangle pattern queries

The following query is the same query that we used in the inverted triangle pattern earlier, with one change. We have replaced the dim_date table (low cardinality) with item (high cardinality).

SELECT i_item_id, SUM(ss_net_paid) AS total_sales
FROM store_sales
JOIN item ON store_sales.ss_item_sk = item.i_item_sk
GROUP BY i_item_id
ORDER BY i_item_id
LIMIT 100;
  • Stage 1: Reads the rows from store_sales and joins with item, spreading data across many partitions—similar to the original query’s first stage.
  • Stage 2: The aggregation is by i_item_id, which normally has thousands to millions of distinct values in real datasets. This keeps parallelism high; many tasks handle non-overlapping keys, and shuffle outputs remain large.

There is no significant drop in cardinality: Because neither stage is reduced to a small group set, most executors stay busy throughout the job’s main phases, with little idle time even after the shuffle. This type of query results in a flatter executor utilization profile because each stage processes a similar volume of work, thus minimizing variation in resource utilization. These rectangle pattern queries will not see the cost benefit from the elasticity obtained by offloading shuffle data. However, there may still be other benefits such as reduction of job failures and performance bottlenecks from disk constraints, freedom from capacity planning and sizing, and provisioning of storage for intermediate data operations.

Conclusion

Serverless storage for Amazon EMR Serverless can deliver substantial cost savings for workloads with dynamic resource patterns, as seen in the 26% average cost savings we observed in our testing environment. By externalizing shuffle data, you can gain the elasticity to release idle executors immediately, demonstrated by the savings reaching up to 85% in our testing environment, on queries following inverted triangle and hourglass patterns when Dynamic Resource Allocation is enabled.Understanding your workload characteristics is key. While rectangle pattern queries may not see dramatic cost reductions, they can still benefit from improved reliability and removal of capacity planning overhead.

To get started: Analyze your job execution patterns, enable Dynamic Resource Allocation, and pilot serverless storage on shuffle-heavy workloads. Looking to reduce your Amazon EMR Serverless costs for Spark workloads? Explore serverless storage for EMR Serverless today.


About the authors

Sekar Srinivasan

Sekar Srinivasan

Sekar has over 20 years of experience working with data. He is passionate about helping customers build scalable solutions modernizing their architecture and generating insights from their data. In his spare time he likes to work on non-profit projects, especially those focused on underprivileged Children’s education.

Praveen Mohan Prasad

Praveen Mohan Prasad

Praveen is a data and AI Specialist with 10+ years of experience in distributed data systems and machine learning, specializing in Information Retrieval and vector search systems. Active open-source contributor and technical speaker in the ML-Search and Agentic-AI space.

The collective thoughts of the interwebz