Tag Archives: prompt engineering

How we make AI coding more cost efficient without sacrificing task quality

Post Syndicated from Erik Kristensen original https://github.blog/ai-and-ml/github-copilot/how-we-make-ai-coding-more-cost-efficient-without-sacrificing-task-quality/


Output quality is important when working with AI coding agents, but true efficiency comes from getting work done quickly, efficiently, and with the right context.

That’s why token count of individual interactions alone isn’t a meaningful measure of efficiency. The goal shouldn’t be to use fewer tokens, but to tap into the right amount of context to move a task forward. A concise tool response can sometimes require additional calls or work if it leaves out information the agent needs, ultimately making the task slower and more expensive.

That’s why we want to optimize for the outcome rather than the tool call. This post examines four changes in GitHub Copilot that put that principle into practice:

  • Preserve useful context while reducing repetitive output.
  • Remove formatting that adds no value to the task.
  • Shorten instructions without changing useful behavior.
  • Deliver completed background work without an extra retrieval step.

Possible changes were evaluated offline using agentic coding benchmarks. The most promising changes were then validated through controlled online experiments before shipping. The examples in this post come from GitHub Copilot CLI. Multiple other Copilot products, such as the GitHub Copilot app and Copilot code review, use the same underlying harness and also become more efficient through these improvements.
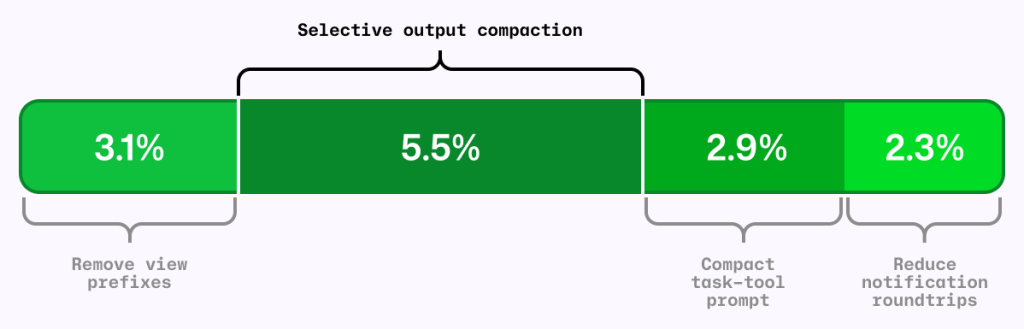
Chart showing 3.1% 'Remove view previxes', 5.5% 'Selective output compaction', 2.9% 'Compact task-tool prompt', and 2.3% 'Reduce notification roundtrips'.
Figure 1: Four independent A/B experiments using the same AI-credit metric. The segments are shown together for comparison; their effects are not necessarily strictly additive. 

The local metric trap

It’s common to shorten the output from each tool call as a way to reduce agent costs. RTK (Rust Token Killer) is a utility that shortens shell output before an agent reads it. We evaluated its effect on GitHub Copilot using our agentic coding benchmarks.

In our harness and benchmark configuration, RTK shortened some responses, but when the omitted text mattered, the model sometimes reopened the original output or reran the command to recover what it needed.

Those recovery steps added turns and carried more context forward. The individual tool response was shorter, but on average, the task used more tokens and took longer. We saved tokens locally and spent more globally.
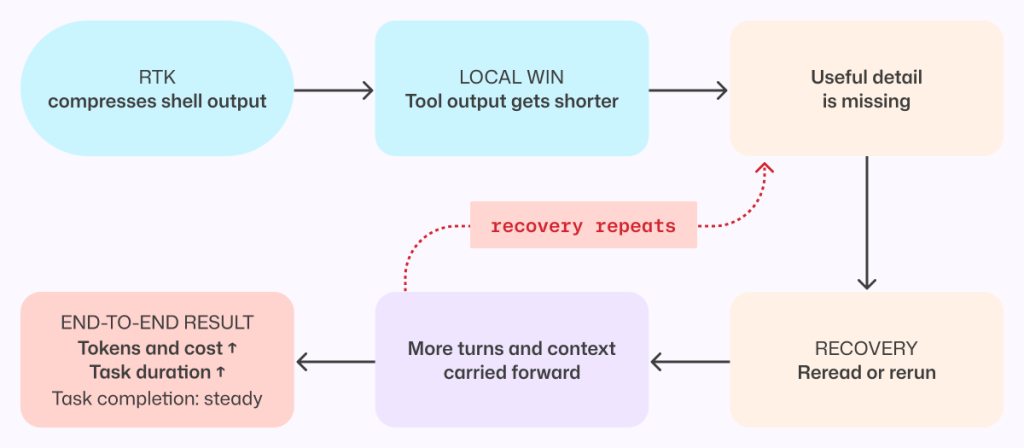
Flow chart showing: RTK, compresses shell output > Local win, tool output gets shorter > Useful detail is missing > Recovery, reread or rerun > More turns and context carried forward. Then the option of finishing at 'End-to-end result, Tokens and cost up, Task duration up, Task completion: steady,' or 'Recovery repeats' going back to 'useful detail is missing'.
Figure 2: A shorter tool response can make the completed task more expensive when missing details force the agent to reread output, rerun commands, and carry more context forward. 

This result applies to the integration and workloads we tested, not to every RTK configuration or to output compression in general. This meant that tokens per tool call is the wrong objective. An efficiency change has to be evaluated across the complete task, from the user’s request through the final result.

More useful was to look at what can we remove without making the model repeat work.

Compress noise, preserve useful information

The goal was to shorten repetitive output while preserving the context an agent needs to complete its task without retracing steps.

Analysis of benchmark runs showed that install, build, test, and lint output often contains repetitive noise, while source-like output and arbitrary command results are more likely to contain the information an agent needs. That analysis informed a selective output compressor, informed in part by RTK and similar approaches.

The prototype was evaluated on agentic coding benchmarks and a range of open source repositories, exercising their build, test, and lint systems.

Early versions were too aggressive. They made the model repeat work or read the full saved output, increasing end-to-end cost and reducing task success. For example, we initially compressed git diff but removed that filter after benchmark tasks showed agents reopening the original output to recover missing information.

Those early failures led to a three-part policy:

  1. Preserve source-like and arbitrary output. Commands such as cat, git diff, git show, and arbitrary scripts are returned unchanged.
  2. Reorganize search results without dropping content. Matches and file lists from tools such as grep can be grouped more efficiently while retaining every result.
  3. Compress repetitive noise selectively. Install, build, test, and progress output is compressed only when the savings are substantial.

The shipped version emerged through repeated evaluation and refinement. It is conservative not because the goal was to build a conservative compressor, but because that is what the evaluations supported.

When output is compressed, the agent can still retrieve the complete original through a direct recovery path.
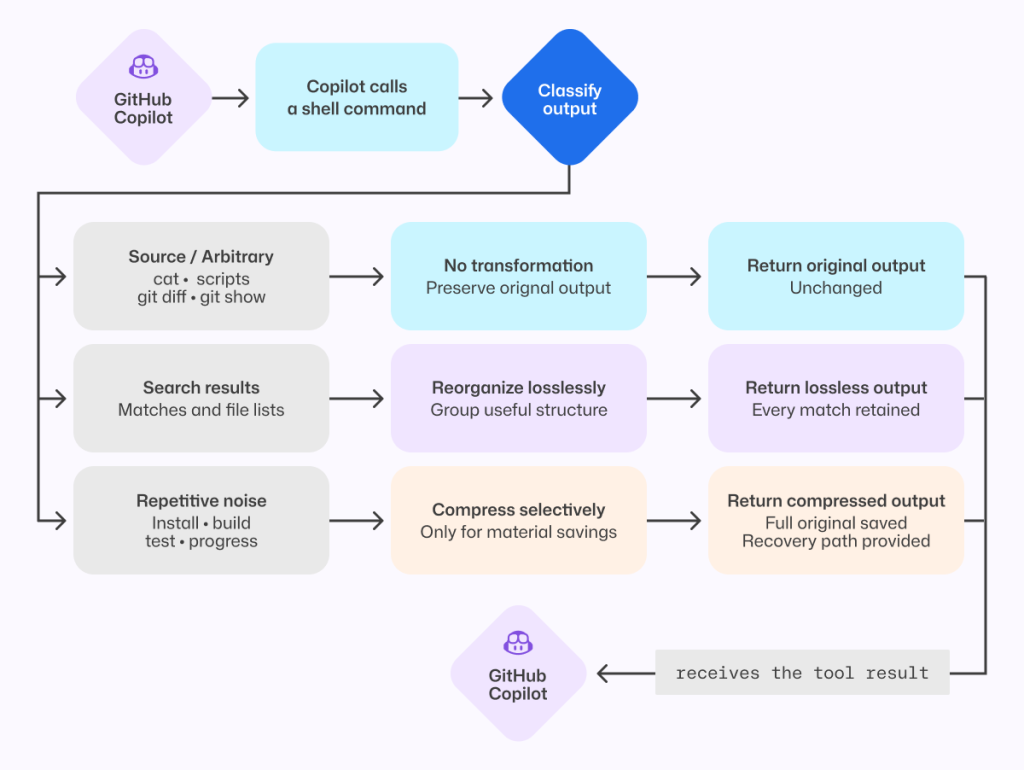
Flowchart showing how GitHub Copilot handles shell-command output. Copilot calls a shell command, classifies the output, then chooses one of three paths: keep arbitrary/source output unchanged, reorganize search results without losing any matches, or selectively compress repetitive noise (like install/build/test logs) while preserving full output and providing a recovery path. The processed result is returned to Copilot.
Figure 3: The shipped compressor preserves source-like output, reorganizes search results without loss, and compresses only predictable repetitive noise while retaining the full original.

That recovery path is both a safety mechanism and an evaluation signal. We tracked whether the agent opened the saved original, reran commands, repeated exploration, narrowed its searches, or took additional turns. Frequent recovery would indicate that the compressor had removed something valuable.

On offline tasks where output compression triggered, no statistically significant task-success regression was detected, and agents extremely rarely opened the saved originals. In the online experiment, average cost decreased slightly with no material regression detected in the tracked quality metrics.

Remove formatting before removing information

One clean token optimization came from the view tool, which agents use to read file contents into context.

Previously, view prefixed every line with a number before showing the contents to the model. Earlier file-editing tools used those numbers to target changes, but current tools instead match surrounding code and do not use line numbers. The line-number prefixes remained even though the normal workflow no longer used them.

Each prefix was small. Repeated across every line and every file read, however, that unused formatting accumulated throughout a session. So, we removed it.
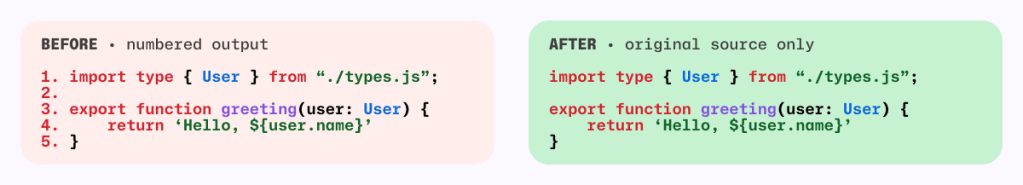
Before-and-after image of code snippets. The line-number prefixes re removed from the 'After' image.
Figure 4: Removing line-number prefixes preserves the source exactly while eliminating formatting that was repeated across every file read.

Line numbers remain useful in diffs and short snippets. They were wasteful here because they were attached to every file read without serving the current editing workflow.

Removing them caused model-inference cost to fall by roughly 5% in offline agentic coding benchmarks. Success rates stayed within the expected run-to-run variance, and edit failures did not increase.

We then tested the change with Copilot CLI users. The online experiment reduced average daily model-inference cost per user by about 3%, with no material regression detected in the quality or satisfaction metrics we tracked.

For developers, that means more of the context window is available for the work itself rather than formatting the agent does not use.

This was the ideal change: no new instructions for the model, no source of information to recover, and no additional decision to make. The file contents reached the model unchanged.

Compress prompts without compressing intent

Prompts carry instructions that shape how an agent works, and they are sent to the model on every turn. Shortening them only improves efficiency if the agent keeps the behaviors developers depend on.

In GitHub Copilot, the task tool launches specialized agents for parallel work. Its guidance had accumulated across tool descriptions, schemas, agent definitions, system instructions, and companion tools.

A meta-prompting loop, in which Copilot iteratively wrote its own prompt, reduced that prompt by roughly half. Copilot produced and refined smaller candidates, and targeted behavioral tests checked the requirements we wanted to preserve.

The first online experiment found a regression that the initial offline evaluations had missed. The meta-prompting loop had rewritten cautious parallelism guidance into a hard scheduling policy, causing independent custom agents to run sequentially.

We stopped the experiment. Before changing the prompt again, we wrote a regression evaluation for the behavior users had exposed. The eventual fix replaced an explicit allowlist and denylist with one sentence:

Independent agents can run in parallel; consider side effects.

That sentence was shorter and less restrictive; it deferred the choice of whether to run sub-agents in parallel to the model instead of the previous explicit guidance. With it, our new behavior test passed without causing any existing behavioral tests to fail.

Prompt behavior needs tests. If a behavior is not tested, a shorter prompt can remove it without anyone noticing. 
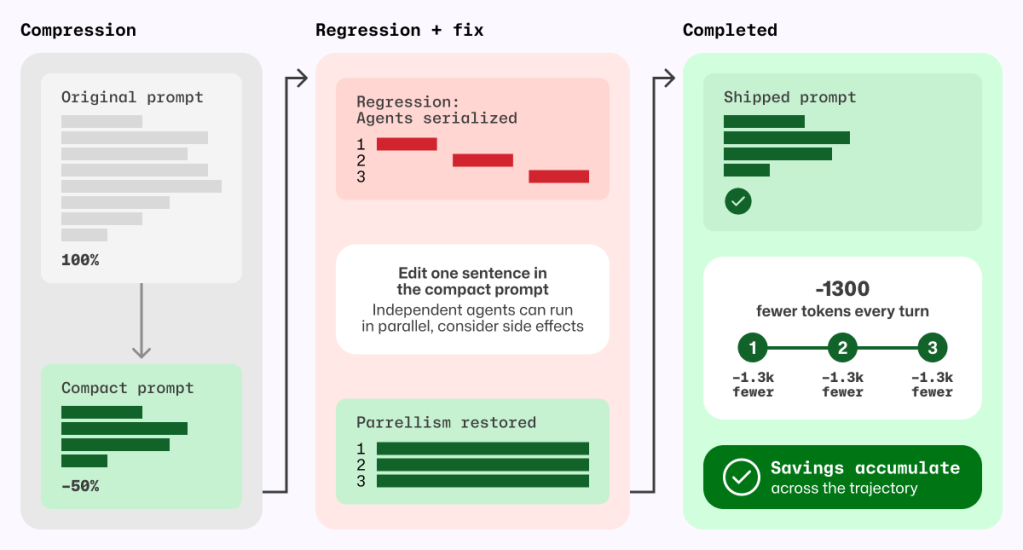
Three-stage diagram labeled Compression → Regression + fix → Completed. Left panel shows an original prompt compressed by about 50%. Middle panel highlights a regression where agents became serialized, then a fix by editing one sentence to restore parallelism. Right panel shows final shipped prompt with restored behavior and cumulative savings of about 1,300 fewer tokens per turn across steps.
Figure 5 Prompt compression became safe only after a regression test exposed serialized agents and a one-sentence fix restored parallelism; the resulting token savings recur on every model turn.

The shipped prompt removes about 1,300 task-tool prompt tokens per turn, corresponding to approximately 1.8% fewer total prompt tokens per session and 2.9% lower normalized cost per active hour, with no quality regression detected in the measured evaluations.

Deliver completed background work without an extra retrieval turn

Agents often run independent work in the background, such as a long-running shell command alongside a sub-agent investigation. Notifications let the agent continue until that work is ready without spending a tool call waiting.

If the agent does not explicitly wait for either task, the harness wakes the model and notifies it when the shell command or sub-agent finishes.

Previously, that notification did not include the completed result, so the agent had to spend another turn retrieving output Copilot had already received. When several tasks finished close together, that detour could repeat. Copilot now batches eligible completion notifications and delivers completed results directly in the existing tool-result format. The agent can continue with the information it needs, without spending an extra turn asking for it again. Explicit reads for work that is still running behave as before.
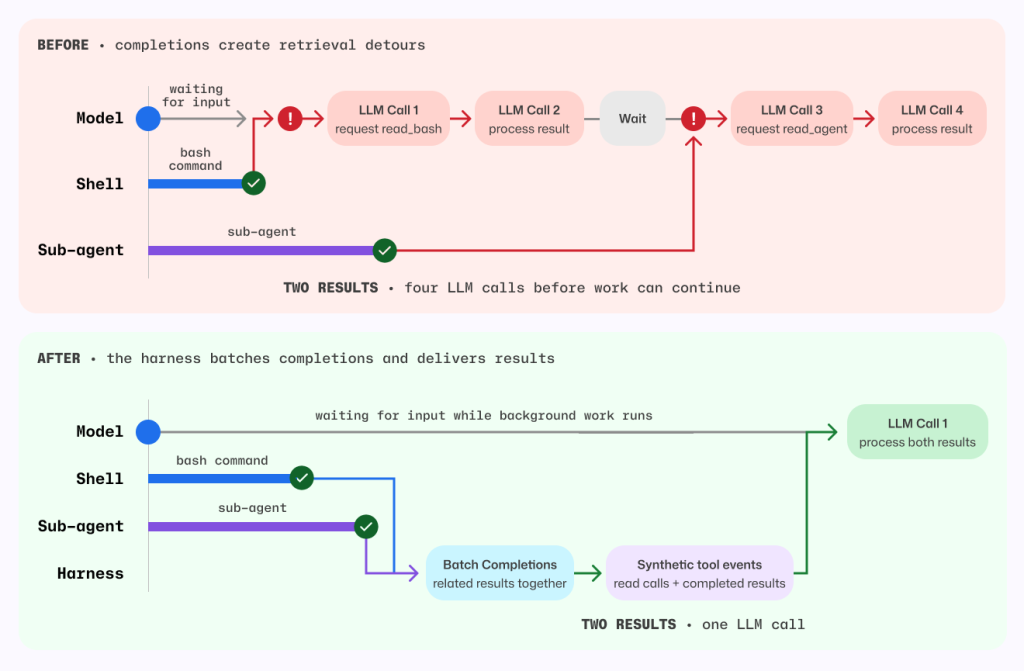
Before-and-after sequence diagram comparing orchestration behavior.

Before: model waits on separate shell and sub-agent completions, causing retrieval detours and four LLM calls to process two results.
After: a harness batches related completions and emits synthetic tool events so background work continues while waiting; both results are processed together in a single LLM call.
The visual emphasizes reduced latency and fewer model round trips.
Figure 6 Before, each background completion could wake a retrieval-only model turn. After, the harness batches eligible completions and delivers completed results in the existing tool-result format.

Before this change, each completed task required one model call to request its result and another to process it. For the shell command and sub-agent shown above, that meant four model calls before work could continue.

Now, the harness batches both completions and supplies their results together, so a single model call can process both. Removing those retrieval detours also avoids carrying the full session context through unnecessary calls.

By delivering completed results directly, without compressing, summarizing, or withholding anything, the harness reduced average token-related usage, as measured in AI Credits, by about 2.3%.

Measure changes in context

A change that saves tokens in one Copilot workflow can increase costs in another.

For example, a tighter set of file-tool instructions was inspired by positive results in Copilot code review. In a Copilot CLI online experiment, it increased cost, so we did not ship it.

By contrast, removing line-number prefixes and selectively compressing output each reduced average prompt tokens per review by roughly 5% in independent evaluations across a large set of Copilot code review tasks using the production model. We detected no material change in the tracked review-quality metrics.

These findings are separate from the earlier migration of Copilot code review to the shared file tools, which, together with review-instruction tuning, reduced code review cost by about 20%.

Each change needs to be measured in the workflow where it runs.

Five lessons for building efficient AI coding agents

  1. Optimize the completed task, not the tool call. Shorter output is not cheaper if the agent spends more turns recovering what was removed.
  2. Optimize orchestration, not just model output. Eliminate model turns that perform work the harness can complete deterministically.
  3. Compress by what the output represents. Preserve exact content, prefer lossless transformations, and measure how often agents use the recovery path.
  4. Prompt rewrites sometimes have unintended consequences. Validate that intended behavior is preserved.
  5. Evidence is local to the workload. Re-evaluate changes in offline benchmarks, online experiments, and every product surface where they ship.

None of these changes made the model smarter. They removed work the model never needed to do.

The changes described in this post are shipping across GitHub Copilot experiences that use the same underlying harness.

Bring agentic workflows to your terminal
with GitHub Copilot CLI >

The post How we make AI coding more cost efficient without sacrificing task quality appeared first on The GitHub Blog.

How to build a GPT-3 App with Nextjs, React, and GitHub Copilot

Post Syndicated from Kedasha Kerr original https://github.blog/2023-07-25-how-to-build-a-gpt-3-app-with-nextjs-react-and-github-copilot/

At the beginning of the year, I started working out with a trainer who wanted me to start tracking my food, but I’ve always been super against tracking my meals because it just doesn’t work for me. Instead of tracking my meals however, I decided to build an application that automagically tells me the nutritional information of any recipe. But to do that I needed some pretty complex natural language parsing capabilities so I figured this would be a great opportunity for me to play around with OpenAI and get to use GitHub Copilot a little bit more to help me build the app quickly.

GitHub Copilot is a great example of a product that takes advantage of Large Language Models (LLM) to solve problems for people and improve their productivity. In this blog,I’ll take you through how I created my own application that finds the nutritional information for any recipe using OpenAI’s GPT-3.5-turbo model, GitHub Copilot, Next.js, React, and Material UI.

Let’s dig right into the tutorial.

1. Create a repository and install dependencies

To get started, let’s create a new repository from the GitHub Codespaces Next.js template to get up and running quickly. Go to this repository, and make a copy. To do so, click on the green “Use this template” button then select “Create a new repository” and name your repository whatever you like. I called mine “mealmetrics-copilot.”

Now, clone the repository to your local machine, and open up the repository in your preferred code editor. I’m using VS Code.

Open up your terminal and cd into the project so we can install a few needed dependencies. In your terminal run the following command:

npm i express openai dotenv @material-ui/core @material-ui/icons

Then, install the following as a dev dependency:

npm i --save-dev nodemon

Once everything installs successfully, we’re ready to start building the server, but first, let’s grab our api key from OpenAI.

2. Getting your OpenAI API key

Go to OpenAI’s developer login page and create a new account or sign in if you already have one. Once you’ve logged in, click your name in the upper right hand corner and select “view API keys.” Click the “Create a new secret key” button. From there you can name your apikey, click the green button to generate the key and then copy the apikey and save it in a secure location (such as a password manager).

Save your apikey in a .env file in vscode at the root of the project and add .env to the gitignore file.

3. Install GitHub Copilot extension

We’ll be using GitHub Copilot as our assistant to build this application. If you’re not familiar with GitHub Copilot, read this blog post to learn more.

In your code editor of choice, go to your extensions panel and search for GitHub Copilot—I’m using VSCode and this is what that looks like.

Click the install button then click the login button to authenticate your access. Once that’s done, you’ll be ready to get started and follow along!

4. Building the server

Now that we have our apikey, have installed dependencies, and have GitHub Copilot in our code editor, let’s dig into building the application!

The first thing we’re going to do is build a simple server with Express.js (if you prefer to use Fastify, NestJS, Koa or something else, feel free to use them!).

In the pages folder, create a folder called api and then a file called server.js. This is where we’ll add our prompting information for GitHub Copilot. Let’s add our first prompt as a comment in the server.js file that says the following:

Create a server with the following specifications:

1. import express and dotenv node modules
3. create the server with express and name it app
4. use port 8080 as default port
5. enable body parser to accept json data
6. state which port the server is listening to and log it to the console

Hit the enter key and GitHub Copilot will start generating suggestions to build the server. To accept the suggestions, hit the tab key. Take a look at this video to see what accepting suggestions look like.

We can update the package.json file to include the script devserver: "nodemon pages/api/server.js then run the command in our terminal using npm run devserver. You’ll see that the server has started!

After we build the simple server, let’s move on to making this a bit more complex by building the controller for our app.

Let’s create a new file in the api folder called generateInfo.js and add the following comment in the file:

Create a controller with the following specifications:

1. import the Configuration class and the OpenAIApi class from the openai npm module
2. create a new configuration object that includes the api key and uses the Configuration class from the openai module
3. create a new instance of the OpenAIApi class and pass in the configuration object
4. create an async function called generateInfo that accepts a request and response object as parameters
5. use try to make a request to the OpenAI completetion api and return the response
6. use catch to catch any errors and return the error include a message to the user
7. export the generateInfo function as a module

As you’ll notice, I’m being very explicit in my instructions to GitHub Copilot. One thing to always remember when working with LLMs is that the magic is in the prompt—the clearer you are in your instructions, the better the results you’ll get.

Hit enter on your keyboard and then hit tab to accept the recommendations that GitHub Copilot provides. In the image below, you’ll notice that Copilot’s suggestions are gray.

Accept the suggestion by hitting tab on your keyboard and let’s do some cleaning up.

Remember, GitHub Copilot is our assistant, so we still need to ensure that the suggestions it provides meet our requirements.

Since we’re building a gpt-3 application, we’ll be using the completion API from OpenAI and the gpt-3.5-turbo model to generate nutritional information for us.

If you look at the suggestion above, we were provided with the davinci engine and parameters that are not needed for this project—we also need the messages parameter to send requests with the 3.5-turbo model.

We also want to add the recipe prompt, create a function called recipe that represents the recipe a user inputs and also update the completion object sent to OpenAI. The keys we’ll be using are max_tokens, prompt, model, temperature and n. Learn more about these parameters by reading OpenAI’s api docs.

Let’s also update the error message to include 401 just in case our api key is invalid. So, let’s make these updates.

1. Add recipe prompt

Create a new folder called data at the root of your project, then create a file called prompt.json. This will contain a part of the recipe prompt that we’ll send to OpenAI. Add the following script to the prompt.json file:

{
"recipePrompt": "I want you to act as a Nutrition Facts Generator. I will provide you with a recipe and your role is to generate nutrition facts for that recipe. You should use your knowledge of nutrition science, nutrition facts labels and other relevant information to generate nutritional information for the recipe. Add each nutrition fact to a new line. I want you to only reply with the nutrition fact. Do not provide any other information. My first request is: "
}

Then import the recipePrompt to the generateInfo.js file and update the main function to grab the recipe submitted by the user.

// add the prompt to the top of the file
const { recipePrompt } = require('../../data/recipe.json');

// update this function to include the recipe before the try
const generateInfo = async(req, res) => {
const { recipe } = req.body
}

2. Update the completion function and response

Now, let’s update the try to look a bit more like what we want.

model: "gpt-3.5-turbo",
messages: [{ role: "user", content: `${recipePrompt}${recipe}` }],
max_tokens: 200,
temperature: 0,
n: 1,

And let’s also update the response that we receive.

const response = completion.data.choices[0].message.content;

return res.status(200).json({
success: true,
data: response,
});

3. Update the error message

Finally, let’s update the catch to have more explicit error messages.

catch (error) {
if (error.response.status === 401) {
return res.status(401).json({
error: "Please provide a valid API key.",
});
}
return res.status(500).json({
error:
"An error occurred while generating recipe information. Please try again later.",
});
}

Once we’ve updated everything, our controller function should look like this:

const { Configuration, OpenAIApi } = require("openai");
const { recipePrompt } = require("../../data/recipe.json");

const config = new Configuration({
apiKey: process.env.OPENAI_API_KEY,
});

const openai = new OpenAIApi(config);

const generateInfo = async (req, res) => {
const { recipe } = req.body;

try {
const completion = await openai.createChatCompletion({
model: "gpt-3.5-turbo",
messages: [{ role: "user", content: `${recipePrompt}${recipe}` }],
max_tokens: 200,
temperature: 0,
n: 1,
});
const response = completion.data.choices[0].message.content;

return res.status(200).json({
success: true,
data: response,
});
} catch (error) {
console.log(error);
if (error.response.status === 401) {
return res.status(401).json({
error: "Please provide a valid API key.",
});
}
return res.status(500).json({
error:
"An error occurred while generating recipe information. Please try again later.",
});
}
};

module.exports = { generateInfo };

Now, let’s create the router and test this out in Postman. Create a new file called router.js and start typing to allow GitHub Copilot to assist you while typing.

As you can see, GitHub Copilot offered suggestions while I was typing and I hit the tab button to accept the suggestions. Add the newly created router to the server.js file and test the route in postman. Add the following to your server.js file.

app.use('/openai', require('./router'));

Now, let’s test the route in postman with a POST request—make sure your server is still running!

Go to the URL below and add any recipe to the body of the request:

URL: http://localhost:8080/openai/generateinfo

RECIPE:
{
"recipe": "1 cup of all purpose flour, sifted 1 1/2 teaspoon baking powder 1/4 teaspoon salt 2 Tablespoon granulated sugar 1/2 Tablespoon unsalted butter, room temperature Approximately 1/3 cup water"
}

You should receive a successful response that looks like this:

{
"success": true,
"data": "\n\nCalories: 112 \nTotal Fat: 2.3g \nSaturated Fat: 1.3g \nTrans Fat: 0g \nCholesterol: 5.4mg \nSodium: 175.8mg \nTotal Carbohydrates: 21.6g \nDietary Fiber: 0.8g \nSugars: 6.5g \nProtein: 2.6g"
}

Here is the data that we submitted to OpenAI that generated that successful response:

data: '{"model":"text-davinci-003","prompt":"I want you to act as a Nutrition Facts Generator. I will provide you with a recipe and your role is to generate nutrition facts for that recipe. You should use your knowledge of nutrition science, nutrition facts labels and other relevant information to generate nutritional information for the recipe. Add each nutrition fact to a new line. I want you to only reply with the nutrition fact. Do not provide any other information. My first request is: 1 cup of all purpose flour, sifted 1 1/2 teaspoon baking powder 1/4 teaspoon salt 2 Tablespoon granulated sugar 1/2 Tablespoon unsalted butter, room temperature Approximately 1/3 cup water","max_tokens":200,"temperature":0.5,"n":1}',

As you can see, both the prompt script and the recipe entered in the request body was sent to OpenAI, which generated the nutritional data for this Jamaican fried dumpling recipe.

Now, let’s create the frontend of the application to display the info on the web.

5. Building the frontend app

We’ll be using React for the frontend. Delete all the code in the index.js file that currently exists in the project. Then, in a comment, instruct GitHub Copilot to build a simple text area.

Create a text area with the following specifications:
1. a H1 with the text "Find Nutrition Facts for any recipe"
2. a text area for users to upload recipe
3. a button for users to submit the entered recipe
4. a section at the bottom to display nutrition facts
5. Get the data from this link: http://localhost:8080/openai/generateinfo
6. Name the component RecipeInfo

GitHub Copilot quickly generated the code for us.

Let’s hit tab to accept the suggestion and run npm run dev in your terminal to see the app on the web. When you go to localhost:3000, you’ll see the following displayed on the web.

Admittedly, it’s not the most beautiful thing, but we were able to spin this up very quickly.

In less than one minute we completed a functional frontend mvp of our application with GitHub Copilot.

Let’s enter the recipe we have into the text box and see the response that we get back.

And we have our first error—which is not surprising since we didn’t validate the code that was provided. Let’s look into the console and see if we have any additional details.

Seems it’s a CORS issue—classic. Let’s ask GitHub Copilot how to resolve this.

Add the following questions as a comment anywhere in your file:

q: how do I resolve the CORS error?
q: how do I add Access-Control-Allow-Origin to the header?

The question and response should look something like this:

We can also ask GitHub Copilot Chat how to resolve CORS errors and it gives us a seamless response.

Let’s install the cors middleware and add it to the server.js file.

const cors = require("cors");

// Allow cross-origin requests (CORS)
app.use(cors());

Then, let’s update our router.js file.

router.options("/generateInfo", (req, res) => {
res.setHeader("Access-Control-Allow-Origin", "*");
res.setHeader("Access-Control-Allow-Headers", "*");
res.setHeader("Access-Control-Allow-Methods", "*");
res.sendStatus(200);
});

Now, let’s try fetching nutritional data again and see what happens.

And we have another error. Progress!

This time there’s no need to debug with GitHub Copilot since we’re being told that the data being returned is an object with the keys success and data. Let’s change the name of the response function to recipeInfo and update the nutrition state to receive recipeInfo.data.

const recipeInfo = await response.json();
setNutrition(recipeInfo.data);

Let’s try sending the recipe again and hope for a successful response.

Success!

We just created a GPT-3 app in record time with GitHub Copilot, React, Next.js, and OpenAI. Now that we have the data that we need, let’s make the application more beautiful with Material UI.

6. Styling the app with Material UI

In this section, we’ll be using a GitHub Copilot X feature in technical preview for individuals and in public beta for organizationsCopilot Chat–to improve the appearance of our application. You must have GitHub Copilot access to be on the Copilot Chat’s waitlist which is currently open. Sign up today if you haven’t yet!

Let’s ask GitHub Copilot chat how we can implement material-ui into the application:

Let’s go ahead and implement the suggestions and see what happens, and also ask GitHub Copilot chat to implement a header for us.

After we implement the header, new text area and center the content, this is what the app is looking like.

Ok, we’re getting somewhere.

Let’s make a few more updates with the assistance of GitHub Copilot Chat. I’ve included the prompt/questions I asked:

  • Make the text area larger and implement Material UI
update the component to use material ui with the content centered and the buttoned positioned below the text area. use Grid from material ui and any other components needed.
  • Add the paper component from Material UI to elevate the look and feel of the app
add the Paper component from material ui to the text area highlighted
  • Add a second button that clears the text area + facts after a recipe is submitted
add a button to the app to clear the text in the textarea
  • Add a loader while waiting for the data to load
add a loader to the highlighted code that checks if the data is loading. If the data is loading, then display the text "Nutrition Facts" and loader, if there is an error, display the error message otherwise, display nothing
  • Add a theme with custom primary and secondary colors
how do I create a custom theme with material ui and where do I create the custom theme?
  • Prevent the text area from going over the paper component from Material UI
in the highlihghted code how do I prevent the text area line from going over the paper component?
  • Add a new component—footer
Create a footer component with the following specifications:
1. The footer must be fixed at the bottom of the page
2. Use the Paper component from Material UI
3. Use the Typography component from Material UI
3. The text must say "Made with ❤ by LadyKerr & GitHub Copilot" and "Powered by OpenAI"
4. The text "GitHub Copilot" must be a link to https://copilot.github.com/ that opens in a new tab with alt text " GitHub Copilot"
5. The text "OpenAI" must be a link to https://openai.com/ that opens in a new tab with alt text "openai api"

Ask GitHub Copilot chat to make the changes above and, once it’s done, your application should be looking and functioning like this:

Now, let’s create a new component that splits each nutrition fact onto a new line. Create a new file called NutritionFacts.js in the components folder, and write the following as a comment so GitHub Copilot can get to work.

Create a component with the following specifications:
1. the component must split the received string data at /n/n or /n and return a Typography component for each string
2. the component must set a unique key for each Typography component
3. the component must return a div with the Typography components
4. the component must return null if the data is not a string
5. Name the component NutritionFacts
6. Use the Paper Component from Material UI
7. Add text above the data that says "Here are the nutrition facts for your recipe:"

From this prompt, GitHub Copilot generated the following code.

import React from "react";
import { Typography, Paper } from "@material-ui/core";

const NutritionFacts = ({ data }) => {
if (typeof data !== "string") {
return null;
}
const nutritionFacts = data.split(/\n\n|\n/);
return (

Here are the nutrition facts for your recipe:

{nutritionFacts.map((fact, index) => (
{fact}
))}
);
};

export default NutritionFacts;

Brilliant! Let’s import this component into our main index.js file and test the application to see if each fact was split on to a new line as expected.

And it did. Our app is functioning as expected.

Now, let’s move the code for the header into a new file in the components folder called Header.js. Once everything is updated, the final application looks like this and returns the nutritional data for any recipe.

So, there we have it!

We just built an application using GitHub Copilot, OpenAI, React, Next.js, and GitHub Copilot Chat. The next step would be to deploy the application on GitHub Pages and deploy your server on a service like Azure.

You can see the full code here—feel free to clone or fork the project and make it your own. This was a fun little project to build and I hope you learned something new and feel inspired to create your own GPT-3 app!

Learn more about prompting GitHub Copilot by reading How to use GitHub Copilot: Prompts, tips and use cases and A Developer’s Guide to Prompt Engineering and LLMs.

Until next time, happy coding!

A developer’s guide to prompt engineering and LLMs

Post Syndicated from Albert Ziegler original https://github.blog/2023-07-17-prompt-engineering-guide-generative-ai-llms/


In a blog post authored back in 2011, Marc Andreessen warned that, “Software is eating the world.” Over a decade later, we are witnessing the emergence of a new type of technology that’s consuming the world with even greater voracity: generative artificial intelligence (AI). This innovative AI includes a unique class of large language models (LLM), derived from a decade of groundbreaking research, that are capable of out-performing humans at certain tasks. And you don’t have to have a PhD in machine learning to build with LLMs—developers are already building software with LLMs with basic HTTP requests and natural language prompts.

In this article, we’ll tell the story of GitHub’s work with LLMs to help other developers learn how to best make use of this technology. This post consists of two main sections: the first will describe at a high level how LLMs function and how to build LLM-based applications. The second will dig into an important example of an LLM-based application: GitHub Copilot code completions.

Others have done an impressive job of cataloging our work from the outside. Now, we’re excited to share some of the thought processes that have led to the ongoing success of GitHub Copilot.

Let’s jump in.

Everything you need to know about prompt engineering in 1600 tokens or less

You know when you’re tapping out a text message on your phone, and in the middle of the screen just above the keypad, there’s a button you can click to accept a suggested next word? That’s pretty much what an LLM is doing—but at scale.

A GIF show autocomplete functionalities in iOS.
An example of iMessage’s text prediction feature.

Instead of text on your phone, an LLM works to predict the next best group of letters, which are called “tokens.” And in the same way that you can keep tapping that middle button to complete your text message, the LLM completes a document by predicting the next word. It will continue to do that over and over, and it will only stop once it has reached a maximum threshold of tokens or once it has encountered a special token that signals “Stop! This is the end of the document.”

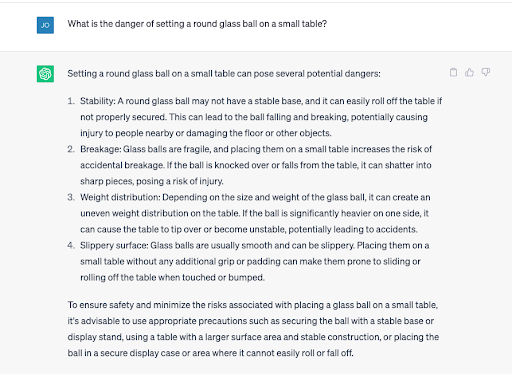
There’s an important difference, though. The language model in your phone is pretty simple—it’s basically saying, “Based only upon the last two words entered, what is the most likely next word?” In contrast, an LLM produces an output that’s more akin to being “based upon the full content of every document ever known to exist in the public domain, what is the most likely next token in your document?” By training such a large, well-architected model on an enormous dataset, an LLM can almost appear to have common sense such as understanding that a glass ball sitting on a table might roll off and shatter.

A screenshot of ChatGPT answering a question about the danger of setting a round glass ball on a small table.
Example of an LLM’s awareness or “common sense” due to its training.

But be warned: LLMs will also sometimes confidently produce information that isn’t real or true, which are typically called “hallucinations” or “fabulations.” LLMs can also appear to learn how to do things they weren’t initially trained to do. Historically, natural language models have been created for one-off tasks, like classifying the sentiment of a tweet, extracting the business entities from an email, or identifying similar documents, but now you can ask AI tools like ChatGPT to perform a task that it was never trained to do.

A screenshot of ChatGPT answering a prompt to create a chicken-based limerick.
John conversing with ChatGPT about serious things.

Building applications using LLMs

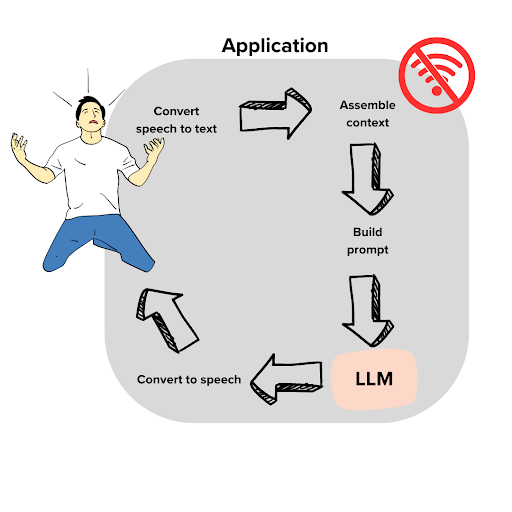
A document completion engine is a far cry from the amazing proliferation of LLM applications that are springing up every day, running the gamut from conversational search, writing assistants, automated IT support, and code completion tools, like GitHub Copilot. But how is it possible that all of these tools can come from what is effectively a document completion tool? The secret is any application that uses an LLM is actually mapping between two domains: the user domain and the document domain.

A graphic showing how LLMs work and the processes behind them to determine context before giving an answer.
Diagram of the user flow when communicating with an LLM, in this case, Dave’s user flow.

On the left is the user. His name is Dave, and he has a problem. It’s the day of his big World Cup watch party, and the Wi-Fi is out. If they don’t get it fixed soon, he’ll be the butt of his friends’ jokes for years. Dave calls his internet provider and gets an automated assistant. Ugh! But imagine that we are implementing the automated assistant as an LLM application. Can we help him?

The key here is to figure out how to convert from user domain into document domain. For one thing, we will need to transcribe the user’s speech into text. As soon as the automated support agent says “Please state the nature of your cable-related emergency,” Dave blurts out:

Oh it’s awful! It’s the World Cup finals. My TV was connected to my Wi-Fi, but I bumped the counter and the Wi-Fi box fell off and broke! Now, we can’t watch the game.

At this point, we have text, but it’s not of much use. Maybe you would imagine that this was part of a story and continue it, “I guess, I’ll call up my brother and see if we can watch the game with him.” An LLM with no context will similarly create the continuation of Dave’s story. So, let’s give the LLM some context and establish what type of document this is:

### ISP IT Support Transcript:

The following is a recorded conversation between an ISP customer, Dave Anderson, and Julia Jones, IT support expert. This transcript serves as an example of the excellent support provided by Comcrash to its customers.

*Dave: Oh it's awful! This is the big game day. My TV was connected to my Wi-Fi, but I bumped the counter and the Wi-Fi box fell off and broke! Now we can't watch the game.
*Julia:

Now, if you found this pseudo document on the ground, how would you complete it? Based on the extra context, you would see that Julia is an IT support expert, and apparently a really good one. You would expect the next words to be sage advice to help Dave with his problem. It doesn’t matter that Julia doesn’t exist, and this wasn’t a recorded conversation—what matters is that these extra words offer more context for what a completion might look like. An LLM does the same exact thing. After reading this partial document, it will do its best to complete Julia’s dialogue in a helpful manner.

But there’s more we can do to make the best document for the LLM. The LLM doesn’t know a whole lot about cable TV troubleshooting. (Well, it has read every manual and IT document ever published online, but stay with me here). Let’s assume that its knowledge is lacking in this particular domain. One thing we can do is search for extra content that might help Dave and place it into the document. Let’s assume that we have a complaints search engine that allows us to find documentation that has been helpful in similar situations in the past. Now, all we have to do is weave this information into our pseudo document in a natural place.

Continuing from above:

*Julia:(rifles around in her briefcase and pulls out the perfect documentation for Dave's request)
Common internet connectivity problems ...
<...here we insert 1 page of text that comes from search results against our customer support history database...>
(After reading the document, Julia makes the following recommendation)
*Julia:

Now, given this full body of text, the LLM is conditioned to make use of the implanted documentation, and in the context of “a helpful IT expert,” the model will generate a response. This reply takes into account the documentation as well as Dave’s specific request.

The last step is to move from the document domain into the user’s problem domain. For this example, that means just converting text to voice. And since this is effectively a chat application, we would go back and forth several times between the user and the document domain, making the transcript longer each time.

This, at the core of the example, is prompt engineering. In the example, we crafted a prompt with enough context for the AI to produce the best possible output, which in this case was providing Dave with helpful information to get his Wi-Fi up and running again. In the next section, we’ll take a look at how we at GitHub have refined our prompt engineering techniques for GitHub Copilot.

The art and science of prompt engineering

Converting between the user domain and document domain is the realm of prompt engineering—and since we’ve been working on GitHub Copilot for over two years, we’ve started to identify some patterns in the process.

These patterns have helped us formalize a pipeline, and we think it is an applicable template to help others better approach prompt engineering for their own applications. Now, we’ll demonstrate how this pipeline works by examining it in the context of GitHub Copilot, our AI pair programmer.

The prompt engineering pipeline for GitHub Copilot

From the very beginning, GitHub Copilot’s LLMs have been built on AI models from OpenAI that have continued to get better and better. But what hasn’t changed is the answer to the central question of prompt engineering: what kind of document is the model trying to complete?

The OpenAI models we use have been trained to complete code files on GitHub. Ignoring some filtering and stratification steps that don’t really change the prompt engineering game, this distribution is pretty much that of individual file contents according to the most recent commit to main at data collection time.

The document completion problem the LLM solves is about code, and GitHub Copilot’s task is all about completing code. But the two are very different.

Here are some examples:

  • Most files committed to main are finished. For one, they usually compile. Most of the time the user is typing, the code does not compile because of incompletions that will be fixed before a commit is pushed.
  • The user might even write their code in hierarchical order, method signatures first, then bodies rather than line by line or in a mixed style.
  • Writing code means jumping around. In particular, people’s edits often require them to jump up in the document and make a change there, for example, adding a parameter to a function. Strictly speaking, if Codex suggests using a function that has not been imported yet, no matter how much sense it might make, that’s a mistake. But as a GitHub Copilot suggestion, it would be useful.

The issue is that merely predicting the most likely continuation based on the text in front of the cursor to make a GitHub Copilot suggestion would be a wasted opportunity. That’s because it ignores an incredible wealth of context. We can use that context to guide the suggestion, like metadata, the code below the cursor, the content of imports, the rest of the repository, or issues, and create a strong prompt for the AI assistant.

Software development is a deeply interconnected, multimodal challenge, and the more of that complexity we can tame and present to the model, the better your completions are going to be.

Step 1: Gathering context

GitHub Copilot lives in the context of an IDE such as Visual Studio Code (VS Code), and it can use whatever it can get the IDE to tell it—only if the IDE is quick about it though. In an interactive environment like GitHub Copilot, every millisecond matters. GitHub Copilot promises to take care of the common coding tasks, and if it wants to do that, it needs to display its solution to the developer before they have started to write more code in their IDE. Our rough heuristics say that for every additional 10 milliseconds we take to come up with a suggestion, the chance it’ll arrive in time decreases by one percent.

So, what can we say quickly? Well, here’s an example. Consider this suggestion to a simple piece of Python:

A developer prompting GitHub Copilot to write a simple function in Python to compute Fibonacci numbers.

Wrong! Turns out the user actually wanted to write Ruby, like this:

A developer using GitHub Copilot to write a simple function to compute Fibonacci numbers in Ruby.

The two languages have similar enough syntax so that only a couple of lines can be ambiguous, especially when it’s toward the beginning of the file where much of what we encounter are boilerplate comments. But modern IDEs such as VS Code typically know what language the user is writing in. That makes language mix ups especially annoying to the user because they break the implicit expectation that “the computer should know” (after all, most IDEs highlight language syntax).

So, let’s put the language metadata into our pile of context we might want to include. In fact, let’s add the whole filename too. If it’s available, it usually implies the language through its extension, and additionally sets the tone for what to expect in that file—small, easy pieces of information that won’t turn the tide but are helpful to include.

On the other end of the spectrum, there’s the rest of the repository. Say you’ve got a file that defines an abstract class DataReader. And you have another that defines a subclass CsvReader. And you’re now writing a new file defining another subclass SqlReader. Chances are that to write the new file, you’ll want to check out both existing files as well because they communicate useful background into what you need to implement and how to do it. Typically, developers keep such files open in different tabs and switch to remind themselves of definitions, examples, similar patterns, or tests.

If the content of those two files is useful to you, chances are it would be useful to the AI as well. So, let’s add it as context! After all, the IDE knows what other files from the repository are open as tabs in the same window. The repository might have hundreds or even thousands of files, but only some will be open, and that is a strong hint that they might be useful to what they’re doing right now. Of course, “some” can mean a lot of things, so we don’t consider any more than the 20 most recent tabs.

Step 2: Snippeting

Irrelevant information in an LLM’s context decreases its accuracy. Additionally, source code tends to be long, so even a single file is not guaranteed to fit completely into an LLM’s context window (a problem that occurs roughly a fifth of the time). So, unless the user is very frugal about their tab usage, we simply cannot include all the tabs.

It’s important to be selective about what code to include from other files, so we cut files into (hopefully) natural, overlapping snippets that are no longer than 60 lines. Of course, we don’t want to actually include all overlapping snippets—that’s why we score them and take only the best. In this case, the “score” is meant to reflect relevance. To determine a snippet’s score, we use the Jaccard similarity, a stat that can be used to gauge the similarity or diversity of sample sets. (It’s also super fast to compute, which is great for reducing latency.)

Step 3: Dressing them up

Now we have some context we’d like to pass on to the model. But how? Codex and other models don’t offer an API where you can add other files, or where you can specify the document’s language and filename for that matter. They complete one single document. As mentioned above, you’ll need to inject your context into that document in a natural way.

The path and name might be easiest. Many files start with a preamble that gives some metadata, like author, project name, or filename. So, we’ll pretend this is happening here as well, and add a line at the very top that reads something like # filepath: foo/bar.py or // filepath: foo.bar.js, depending on comment syntax in the file’s language.

Sometimes the path isn’t known, like with new files that haven’t yet been saved. Even then, we could try to at least specify the language, provided the IDE is aware of it. For many languages, we have the opportunity to include shebang lines like #!/usr/bin/python or #!/usr/bin/node. That’s a neat trick that works pretty well at warding against mistaken language identity. But it’s also a bit dangerous since files with shebang lines are a biased subpopulation of all code. So, let’s do it for short files where the danger of mistaken language identity is high, and avoid it for larger or named files.

If comments work as a delivery system for tiny nuggets of information, like path or language, we can also make them work as delivery systems for the chunky deep dives that are 60 lines of related code.

Comments are versatile, and commented-out code exists all over GitHub. Let’s look at some of the most common examples:

  • Old code that doesn’t apply anymore
  • Deleted features
  • Earlier versions of current code
  • Example code specifically left there for documentation purposes
  • Code lifted from other parts of the codebase

Let’s take our inspiration from the last group of examples. Familiarity with groups (1) – (3) makes things a bit easier on the model, but our snippets aim to emulate groups (4) and (5):

# compare this snippet from utils/concatenate.py:

# def crazy_concat(a, b):

# return str(a) + str(b)[::-1]

Note that including the file name and path of the snippet source can be useful. And combined with the current file’s path, this might guide completions referencing imports.

Step 4: Prioritization

So far, we have grabbed many pieces of context from many sources: the text directly above the cursor, text below the cursor, text in other files, and metadata like language and file path.

In the vast majority of cases (around 95%), we have to make the tough choice of what we can or cannot include.

We make that choice by thinking of the items we might include as “wishes.” Each time we uncover a piece of context, like a commented out snippet from an open tab, we make a wish. Wishes come with some priority attached, for example, the shebang lines have rather low priorities. Snippets with a low similarity score are barely higher. In contrast, the lines directly above the cursor have maximum priority. Wishes also come with a desired position in the document. The shebang line needs to be the very first item, while the text directly above the cursor comes last—it should directly precede the LLM’s completion.

The fastest way of selecting which wishes to fill and which ones to discard is by sorting that wishlist by priority. Then, we can keep deleting the lowest priority wishes until what remains fits in the context window. We then sort again by the intended order in the document and paste everything together.

Step 5: The AI does its thing

Now that we’ve assembled an informative prompt, it’s time for the AI to come up with a useful completion. We have always faced a very delicate tradeoff here—GitHub Copilot needs to use a highly capable model because quality makes all the difference between a useful suggestion and a distraction. But at the same time, it needs to be a model capable of speed, because latency makes all the difference between a useful suggestion and not being able to provide a suggestion at all.

So, which AI should we choose to “do its thing” on the completion task: the fastest or the most accurate one? It’s hard to know in advance, so OpenAI developed a fleet of models in collaboration with GitHub. We put two different models in front of developers but found that people got the most mileage (in terms of accepted and retained completions) out of the much faster model. Since then, further optimizations have increased model speed significantly, so that the current version of GitHub Copilot is backed by an even more capable model.

Step 6: Now, over to you!

The generative AI produces a string, and if it’s not stopped, it keeps on producing and will keep going until it predicts the end of the file. That would waste time and compute resources, so you need to set up “stop” criteria.

The most common stop criterion is actually looking for the first line break. In many situations, it seems likely that a software developer wants the current line to be finished, but not more. But some of the most magical contributions by GitHub Copilot are when it suggests multiple lines of code all at once.

Multi-line completions feel natural when they’re about a single semantic unit, such as the body of a function, an if-branch, or a class. GitHub Copilot looks for cases where such a block is being started, either because the developer has just written the start, such as the header, if guard, or class declaration, or is currently writing the start. If the block body appears to be empty, it will attempt to make a suggestion for it, and only stop when the block appears to be done.

This is the point when the suggestion gets surfaced to the coder. And the rest, as they say, is ~~history~~ 10x development.

If you’re interested in learning more about prompt engineering in general and how you can refine your own techniques, check out our guide on getting started with GitHub Copilot.