Tag Archives: large language models

GenRec: Towards LLM-Native Recommendation at Netflix

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/genrec-towards-llm-native-recommendation-at-netflix-f20be6f643e3

Authors: Ying Li, Arjun Rao, Shradha Sehgal

Introduction

Recommendations sit at the heart of the Netflix experience. Our current production models rely on thousands of hand‑crafted features over users, items, and interactions, along with specialized architectures for sequence modeling, feature interactions, and multi‑task objectives. This stack has evolved over many years to support diverse content types (movies, series, games, live, podcasts) and product surfaces, but its complexity makes it costly to onboard new use cases: adding a content type or surface can require significant feature engineering, architecture change, infrastructure work, and experimentation.

At the same time, large language models (LLMs) are changing how we think about recommendation, as shown by recent work such as PLUM, GLIDE, and OneRec-Think. Their broad world knowledge and strong language understanding make it possible to represent user histories and item metadata directly as text, capture rich relationships in a shared semantic space, and steer recommendations via natural‑language prompts. However, off‑the‑shelf LLMs are still far from production‑ready recommenders: they often over‑recommend globally popular content, hallucinate out‑of‑catalog items, ignore business constraints, and provide only limited personalization.

To address this, we built GenRec, an LLM‑backed recommendation ranker that post‑trains an internal foundation LLM on Netflix‑specific data and objectives. GenRec shows that an LLM‑based ranker can match or exceed a mature production system while relying on far fewer labeled examples and input signals.
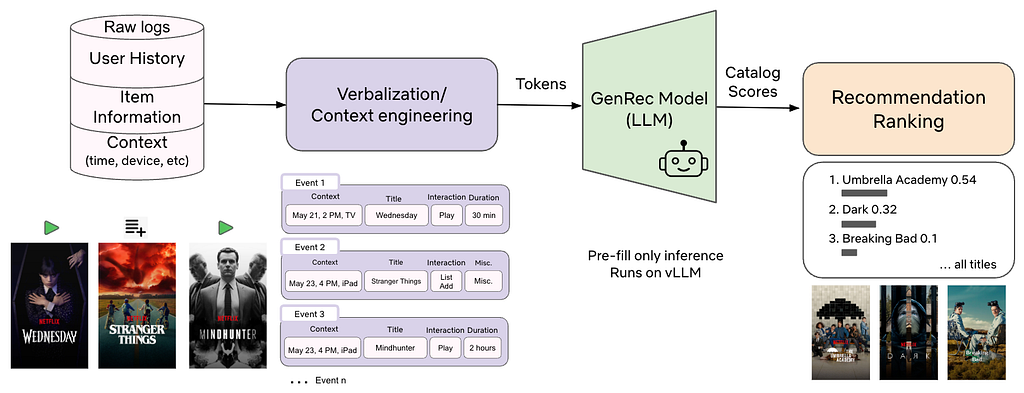
Figure 1: GenRec pipeline. Raw logs of user history, item metadata, and context are transformed via context engineering into natural-language prompts and fed into the GenRec, which runs on vLLM in prefill-only mode and outputs scores for each catalog item, yielding a recommendation ranking.

At a high level, GenRec:

  • Verbalizes user histories, item metadata, and context as text.
  • Post‑trains a Netflix‑adapted foundation LLM for ranking.
  • Adds a catalog‑aware scoring head over Netflix titles.
  • Uses reward signals to align with long‑term member value and business goals.
  • Runs in prefill‑only mode on Netflix’s LLM serving stack for cost efficiency.

In a large‑scale A/B test against a well‑tuned production ranker, GenRec achieves statistically significant improvements in both short‑term and long‑term online metrics, while using only a small fraction of the Phase‑2 labeled data and input signals. It reduces our reliance on hand‑engineered features and shifts the focus from feature engineering to context engineering. In this blog post, we will describe how GenRec works, how it performs, and why we believe it points toward a more LLM‑centric future for recommendation at Netflix.

Problem Setting

We focus on a full‑catalog ranking task (or top‑K ranking when a candidate set is provided).

Given a user 𝑢, their interaction history 𝐻, and the current context 𝜏 (device, surface, locale, time, etc.), GenRec scores each item and produces a personalized ranking that can directly power recommendations or serve as input for downstream personalization systems.

Formally, we map a request (u,τ,t,H) — user, context, time, and history — to a ranking 𝜋 over the catalog C, where π(i) is the position assigned to item i. We optimize π for expected long‑term member utility (a proxy for satisfaction and retention), not just short‑term engagements.

From Foundation LLM to Recommendation Ranker

GenRec follows a two‑phase training framework (Figure 2):
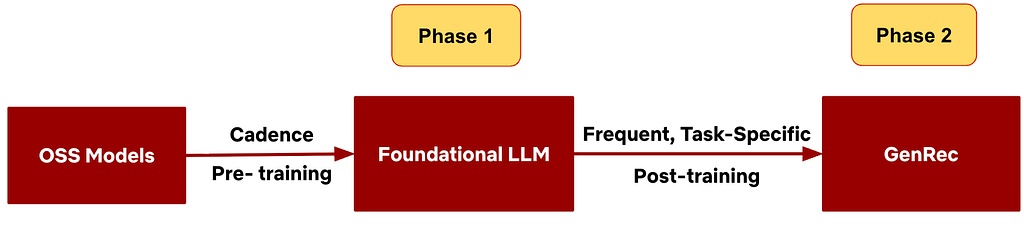
Figure 2: Two Phase Framework. Phase 1 trains a foundational LLM on Netflix data for user and content understanding, and Phase 2 post-trains on ranking-specific data and objectives.

Phase 1 — Netflix-Adapted Foundation LLM.

We start from an open‑source LLM and adapt it on proprietary Netflix corpora, so it learns foundational capabilities such as

  • Netflix content understanding
  • Member behavior and preference patterns
  • General language understanding and generation.

Phase 1 is updated relatively infrequently and serves as a shared, Netflix‑aware backbone for many applications.

Phase 2 — GenRec.

We then turn this foundation model into a high‑quality ranking model by post‑training on ranking‑specific data and objectives. Phase 2:

  • Focuses on ranking quality and steering
  • Incorporates multiple reward signals via reward‑weighted losses
  • Is refreshed more frequently to track new content and evolving tastes
  • Is explicitly optimized under serving cost constraints.

Training Data as Conversations

Netflix members generate hundreds of billions of interaction events spanning many surfaces (views, plays, durations, thumbs up/down, add to list, abandons, etc.). We convert this log data into single‑turn or multi‑turn “conversations” between a user and a recommender. Each turn contains:

  • User message: verbalized context, profile, history, item metadata, and task (e.g., recommend what the user will watch or thumb next).
  • Assistant message: the member’s actual engagement (e.g., which titles were played, for how long, what feedback they provided).

During Phase‑2 training, the LLM learns how assistant messages depend on user messages. This allows us to express rich recommendation signals as text, jointly supporting both the language-modeling (LM) and ranking objectives.

At inference time, we feed in the verbalized context and apply a catalog‑aware scoring head to rank items; we do not decode assistant messages. The conversational format is primarily used during training to support the LM objective and preserve strong language understanding over the verbalized text.

Verbalization and Context Engineering

Traditional recommenders operate on dense features and embeddings. GenRec takes a different approach: it verbalizes rich user histories and context as natural language, encoding raw interaction signals directly in the LLM’s semantic space. In doing so, it relies on the model to discover higher‑level patterns — such as item relationships and evolving user interests — rather than on manual feature engineering.

Naively verbalizing every interaction in a user’s history can quickly exceed the token budget and be too expensive at Netflix scale. The context window becomes our new “feature budget”, so we apply context engineering:

  • Retain in full: high‑signal engagements (e.g., long plays, thumbs‑up) with richer details
  • Omit: low‑signal events (e.g., very short plays or quick hovers)
  • Summarize or compress: repetitive behaviors (e.g., binge‑watching )
  • Elaborate selectively: important or cold‑start items (e.g., new releases)

Within a fixed token budget, we prioritize recent, high‑signal history and compress or drop older history. We also structure the prompt to maximize shared prefixes for better prefix caching. The goal is a compact, high‑information prompt that preserves ranking quality without prohibitive costs.

Objectives: Ranking, Language, and Rewards

The overall GenRec model is trained with a multi‑objective loss that combines a recommendation ranking objective, language modeling objectives, and alignment via reward‑weighted training.

1. Catalog‑Aware Ranking Objective

The primary task is a ranking objective that teaches the model to score items by engagement quality. We label positives using high‑value engagements (e.g., sufficiently long plays, strong explicit feedback), with thresholds and denoising logic, and train the model — via a cross‑entropy loss over the catalog or candidate set — to assign higher scores to these positives given a verbalized context.

2. Language Modeling Objective

We also retain a language modeling (LM) objective over the verbalized inputs and outputs. This helps preserve the model’s general language understanding, improves its ability to interpret rich natural‑language histories and item metadata, and keeps the door open for text‑generation use cases such as recommendation explanations.

3. Reward‑Weighted Loss for Alignment

Beyond raw ranking accuracy, GenRec must (1) respect business requirements — for example, balancing movies, series, games, live, and podcasts — and (2) optimize long‑term member satisfaction rather than just immediate clicks or plays.

Training only on raw interaction sequences can lead to undesirable behaviors, such as over‑favoring binge‑watching or over‑focusing on a single content type. To address this, we weight the ranking loss using signals from separate reward models. Each training example receives a scalar weight derived from two types of signals:

  • Long‑term satisfaction proxies: estimate how much a short‑term engagement contributes to long‑term outcomes, such as return behavior, catalog exploration, or sustained engagement.
  • Behavior rebalancing: adjust behaviors across content types and launch stages (for example, games vs. movies, new releases vs. evergreen titles) to better align with business goals.

The example’s ranking loss is then scaled by this weight: high‑value engagements receive larger weights, and low‑value ones are down‑weighted. This reward‑weighted approach is simpler and more cost-efficient than full reinforcement learning, yet provides effective alignment in practice. We have seen additional gains from RL‑style methods (e.g., GRPO), but leave them to future work due to their higher cost.

Model Architecture and Serving

Backbone and Scoring Head

GenRec’s architecture closely follows our foundational LLM: a decoder‑only Transformer trained with next‑token‑prediction style objectives, augmented with a catalog‑aware ranking head that scores only Netflix in-catalog items. The scoring pipeline works as follows:

  1. Verbalization: A verbalizer V serializes user history H, context 𝜏 , and relevant item metadata into a single text sequence x.
  2. Pooled representation: The LLM processes x, and we extract a pooled hidden state h that summarizes the user’s current preferences and context.
  3. Catalog‑aware scoring: Each catalog item i has a learned embedding eᵢ. A scoring head ϕ combines h and eᵢ (e.g., via dot product or small MLP) to produce a score s. Applying a softmax over scores yields a probability distribution which we convert into a ranking π.

All parameters — the backbone, scoring head, and item embeddings — are trained jointly. For very large catalogs, we can use sampled softmax or candidate sets for efficient training and inference. This architecture constrains recommendations to the Netflix catalog while supporting efficient scoring over large candidate sets.

Serving and Cost Optimization

GenRec is served on Netflix’s internal LLM stack using vLLM. At Netflix scale, serving cost is driven primarily by 1) Model size; 2) Context length; 3) Inference mode (prefill vs. autoregressive decoding). We control cost through three strategies:

  • Smaller / distilled models: We train GenRec on smaller or distilled foundation models, often with larger or more targeted datasets, to capture most of the quality of larger models at lower serving cost.
  • Aggressive context compaction: Using the context engineering described earlier, we minimize tokens while preserving ranking quality.
  • Prefill‑only inference: Autoregressive decoding over large candidate sets would be prohibitively expensive. Instead, we run in prefill‑only mode: the model consumes the prompt once and scores the entire candidate set in a single forward pass, with no token‑by‑token decoding.

Together, these choices make it feasible to serve GenRec on high‑volume workloads within compute budgets.

Offline and Online Experiments

We evaluated GenRec against a mature production ranker that has been tuned over many years. The baseline model relies on thousands of engineered dense and embedding features, as well as custom architectures for modeling feature interactions and sequences. We assessed performance using both offline evaluation metrics and a large‑scale online A/B test.

GenRec vs Production Baseline

Offline, GenRec outperformed the production ranker on ranking metrics despite using far fewer input signals and labeled examples. With roughly 40× fewer Phase‑2 labeled training examples, GenRec achieved about +1.6% improvement in Mean Reciprocal Rank (MRR). As we increased Phase‑2 training data and enriched the input signals, GenRec’s offline metrics continued to improve.

Online, we ran a large A/B test on batch‑compute recommendation surfaces, covering ~10% of Netflix traffic over ~4 weeks. In this low‑data, low‑signal configuration, GenRec delivered statistically significant gains over the production baseline on both short‑term and long‑term online metrics (Figure 3).

These results indicate that a properly post‑trained and aligned LLM‑backed ranker can be a strong alternative to traditional recommendation models, with substantial headroom as we further scale data and input signals.
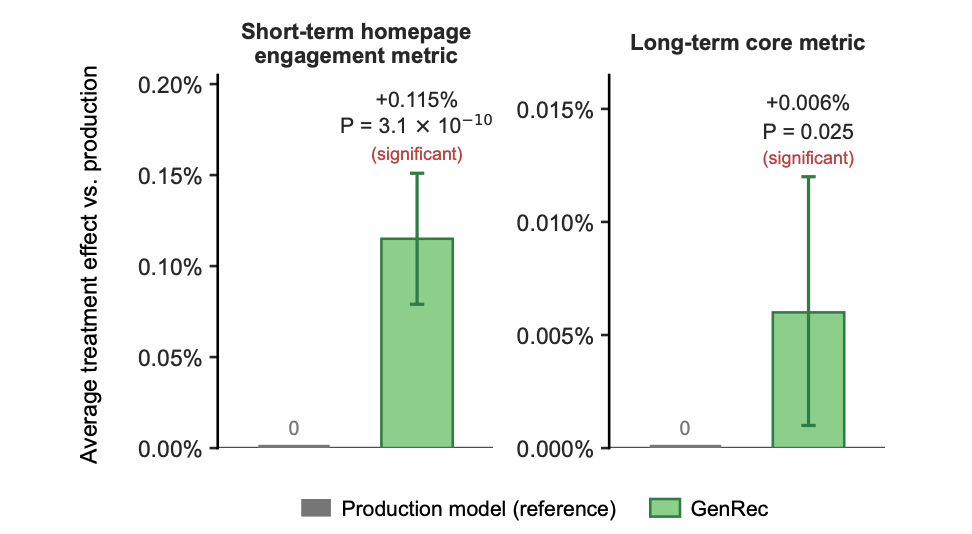
Figure 3: Online metrics of GenRec vs. production model. GenRec achieves statistically significant improvements on both short-term and long-term online metrics.

Data, Model, and Phase Contributions

We ran ablations to understand where GenRec’s gains come from.

Data and Model Scaling

  • Data scaling: For both ~1B and ~10B parameter backbones, offline MRR improves as we increase Phase‑2 post‑training data. Larger models reach higher absolute MRR but follow a similar scaling curve (see Figure 4).
  • Model scaling: Under a fixed training budget, we post‑trained GenRec variants from ~1B to ~10B parameters. Within this budget, larger backbones consistently achieved higher offline MRR than smaller ones.
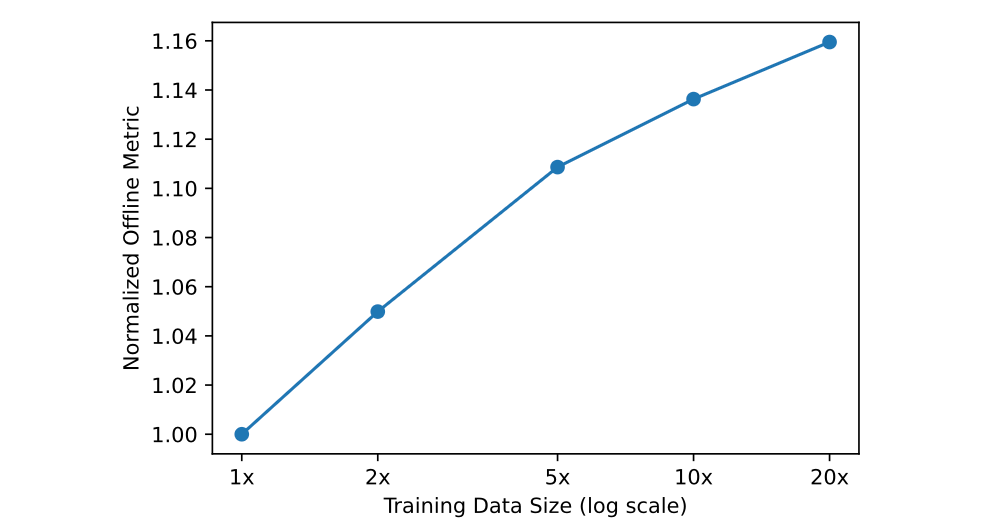
Figure 4: GenRec Phase-2 data scaling for the∼10B model.

Phase-1 vs. OSS, Phase-2 vs. Phase-1

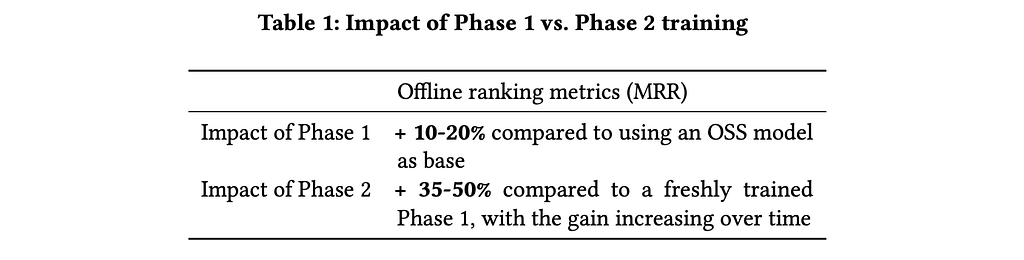
  • Phase-1 vs. OSS: Using the Phase‑1 Netflix‑adapted foundation LLM as the base model improves offline ranking metrics by roughly 10–20% compared to starting directly from an off‑the‑shelf LLM.
  • Phase-2 vs. Phase-1: Phase‑2 post‑training adds another 35–50% gain in offline ranking metrics when evaluated near the Phase‑1 training cutoff (i.e. when Phase‑1 model is the freshest). As time passes and Phase‑1 becomes stale with new content and shifting tastes, the relative benefit of Phase 2 grows to about 80% after 2 weeks.
Data efficiency vs. production ranker

  • Starting from a strong Phase‑1 model, GenRec matches or exceeds the production ranker using 10–40× fewer Phase‑2 labeled examples, depending on configuration. This marginal data efficiency is especially valuable because Phase 2 is refreshed far more frequently than Phase 1.

Context Length Optimization

Context length drives both quality and cost: longer verbalizations expose more behavior and context but increase training and serving cost. To study this trade‑off, we varied context length and verbosity and optimized them in three steps:

  1. Clean and compress events: drop low‑signal engagements and compress repetitive behavior to form a cleaned sequence of events.
  2. Find the “elbow point”: vary how many historical events we include and plot MRR vs. number of events to identify an elbow beyond which additional context yields diminishing returns (see Figure 5).
  3. Optimize verbosity: for the retained events, test different levels of details and simplified wordings, measuring MRR each time.

In our experiments, we can reduce the context tokens to roughly one-third of the original budget with negligible degradation in offline ranking metrics. Since serving cost is approximately proportional to context length, we observed a similar reduction in serving cost.
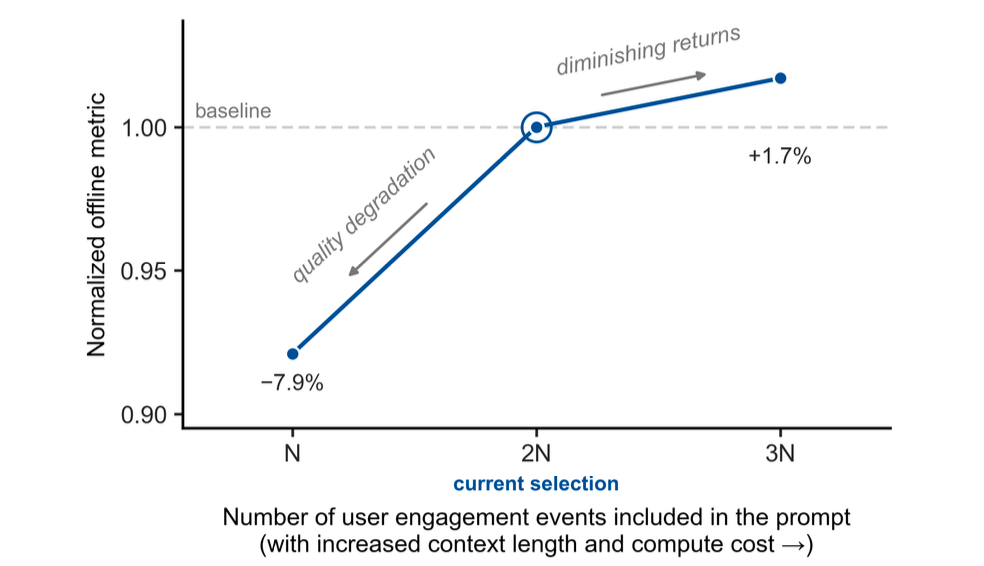
Figure 5: Offline ranking metric (MRR) vs. number of user engagement events included in the prompt. The dashed line marks the elbow point: increasing the number of events beyond this yields diminishing returns.

Towards LLM‑Native Recommendation

GenRec is more than “swapping in a Transformer” for an existing ranker. It hints at a broader shift toward LLM‑native recommendation at Netflix. A few notable changes:

From Feature Engineering to Context Engineering

Traditional RecSys stacks revolve around large feature sets and heavy feature infrastructure. LLM‑centric systems instead revolve around constructing rich textual contexts from raw logs, metadata, and tools. The “prompt” becomes the new feature vector.

Modeling effort shifts from designing features to deciding which signals to include, how far back in time to go, how to compress or summarize history within a token budget. Our experiments on verbalization compaction illustrate this shift: careful context design can preserve quality while dramatically reducing serving cost.

From Customized Architectures to Foundation Backbones

Historically, each recommendation task often had its own custom architecture (two‑tower models, DLRM‑style networks, bespoke attention blocks). In an LLM‑centric world, many tasks share a common foundation backbone, with differentiation coming from data and verbalization strategies, post‑training objectives and rewards, and inference optimization.

GenRec leverages the same backbone as our foundation LLM rather than introducing a new architecture built from scratch. This makes it easier to share learnings across applications, and opens the door to natural‑language steering for future experiences.

Scaling Laws as Design Guides

Traditional RecSys can hit diminishing returns due to sparse IDs, heavy engineering objectives, and task‑specific architectures. With an LLM‑backed backbone, recommendation inherits clearer data and model scaling behavior: within cost limits, more data and larger models consistently improve quality. This brings RecSys design closer to the broader LLM paradigm, where scaling laws help guide model and data investment.

From RecSys Infra to LLM Infra

LLM‑backed recommenders push us toward LLM‑style infrastructure: GPU‑accelerated, vLLM/Triton‑based, with careful batching and caching. Over time, recommendation serving infra starts to look more like general LLM infra than classic RecSys stacks built around MLPs or factorization models.

Conclusions

We have presented GenRec, an LLM‑backed recommendation ranker at Netflix that adapts an internal foundation LLM for large‑scale personalization. By verbalizing user histories, context, and item metadata, adding a catalog‑aware ranking head, using reward‑weighted objectives aligned to long‑term satisfaction and business goals, and serving efficiently on our LLM infrastructure, we obtain a model that improves on a strong production ranker while using far fewer Phase‑2 labels and input signals.

GenRec is an early but promising step toward a more LLM‑centric recommendation stack at Netflix. Our results suggest that, with careful attention to cost, infrastructure, and alignment, LLM‑backed recommenders can play a central role in large‑scale personalization.

Acknowledgments

GenRec is the result of close collaboration among multiple teams and organizations across Netflix. The contributors to this work (in alphabetical order):

AI for members: Arjun Rao, Ashish Rastogi, Baolin Li, Fernando Amat Gil, Grace Huang, Justin Basilico, Kamelia Aryafar, Linas Baltrunas, Moumita Bhattacharya, Ogheneovo Dibie, Rein Houthooft, Shradha Sehgal, Sejoon Oh, Sergi Perez, Sourabh Medapati, Thea Wang, Yaochen Zhu, Yesu Feng, Ying Li, Yun Li, Yucheng Shi, Yunan Hu

AI platform and serving: Abhishek Agrawal, Adam Singer, Binh Tang, Daneo Zhang, Derek Olejnik, Ed Maddox, Erik Osheim, Lingyi Liu, Liping Peng, Meghana Chilukuri, Nicolas Hortiguera, Shaojing Li, ZQ Zhang

Product: Ilke Kaya, Michelle Kislak, Scarlet Chen, Si Cheng


GenRec: Towards LLM-Native Recommendation at Netflix was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.
GenPage: Towards End-to-End Generative Homepage Construction at Netflix

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/genpage-towards-end-to-end-generative-homepage-construction-at-netflix-77146fba8a08

Authors: Lequn Wang, Jiangwei Pan, and Linas Baltrunas

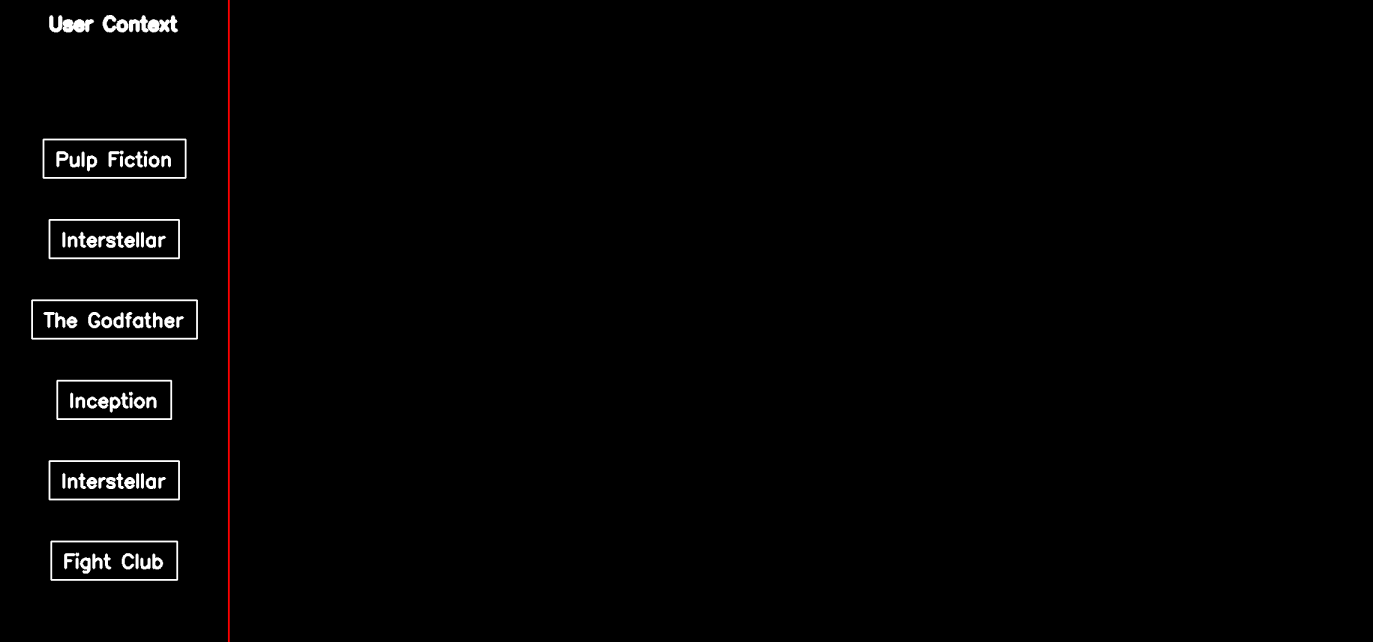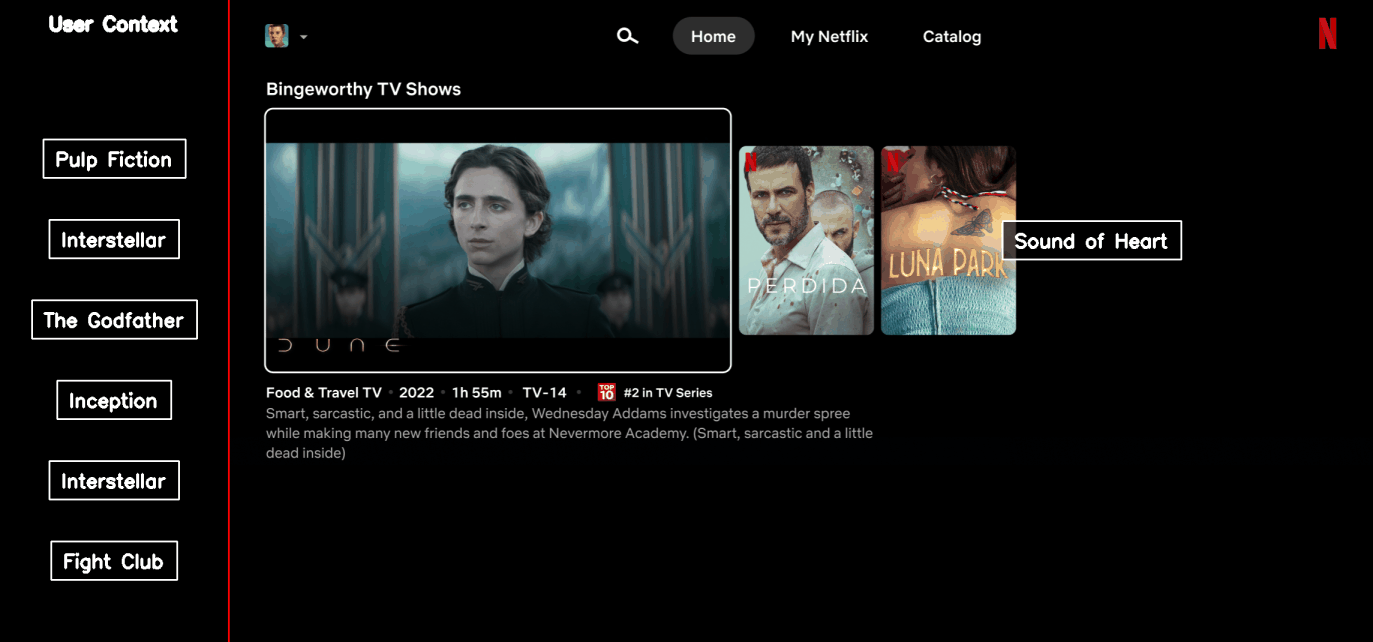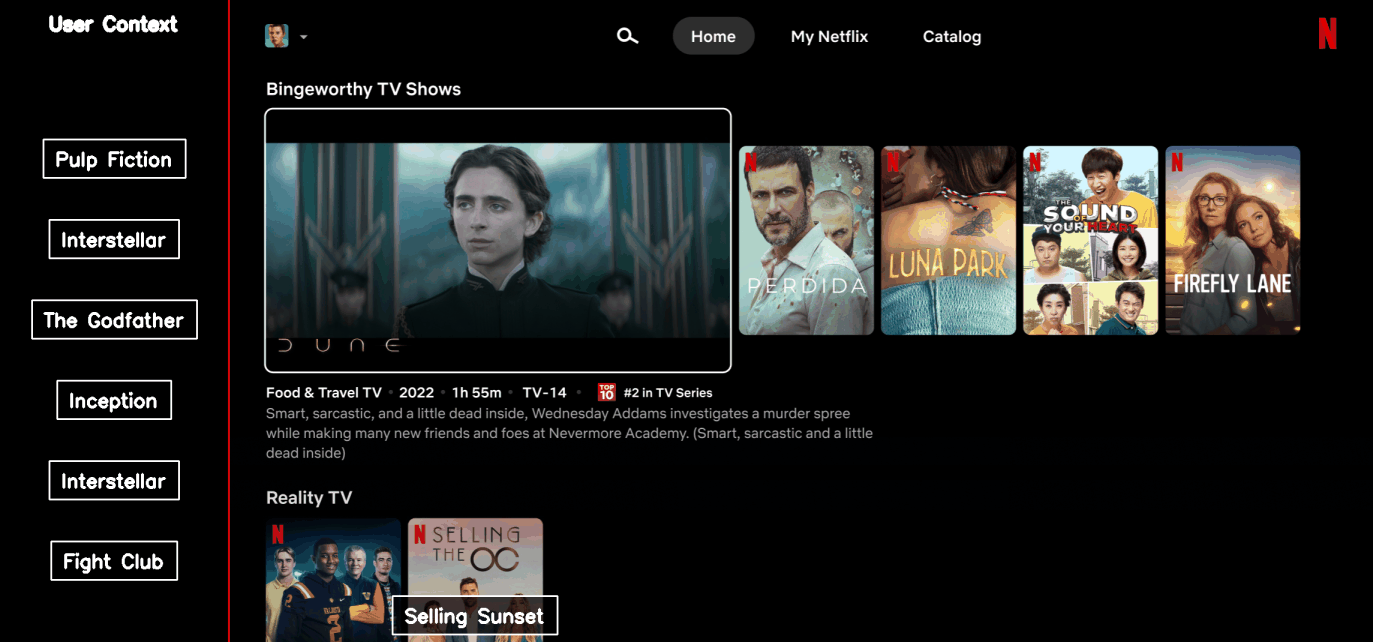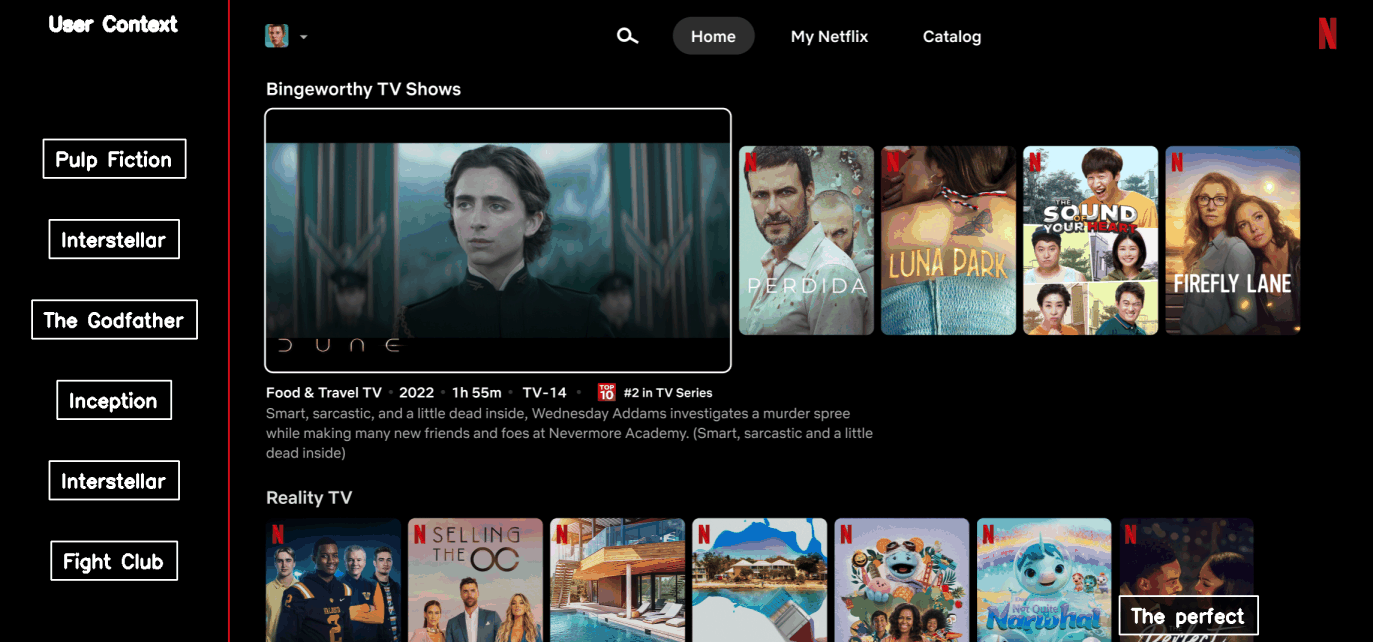
Figure 1. Autoregressive homepage generation. GenPage builds a Netflix homepage one row or entity at a time, each one conditioned on what’s already on the page and the user’s context.

Introduction

The Netflix homepage is the first thing users see when they open the app and the primary way they discover content to enjoy. Almost every part of it is personalized, including which rows appear, which entities show up within those rows, and how everything is arranged on the page.

Constructing that homepage is a genuinely hard problem. It is not simply producing one ranked list. The homepage is a structured, two-dimensional layout, made up of recommendation rows and the entities within them. Here, an entity can be a movie, show, game, live event, or other recommendable item. Each choice can affect the value of the others. Traditionally, it is built through a complex, multi-stage pipeline, with separate components for candidate generation and ranking at both the row and entity levels.

We saw an opportunity to rethink this design. Large language models have shown that a single generative model can perform diverse tasks just by generating a response to a prompt. Inspired by this prompt-response paradigm, we trained a single generative model to build the homepage by directly answering one question:

Given everything we know about this user and this request, what homepage should we generate to maximize user satisfaction?

We call this approach GenPage. It treats the user history and request context as the prompt, and autoregressively generates the entire homepage as the response (Figure 1). Unlike most generative recommenders, such as TIGER, HSTU, and OneRec, which generate flat ranked lists, GenPage generates the rows, entities, and layout together.

This shift is motivated by several goals:

  • End-to-end modeling. A single transformer model that constructs the page from raw input signals can replace a complex multi-stage recommender stack. This reduces the number of ML models to maintain, avoids misaligned objectives across stages, and eliminates much of the traditional feature engineering.
  • Whole-page optimization via reinforcement learning (RL). Autoregressive page generation makes it possible to optimize for page-level rewards with RL. This can capture interactions across rows and entities, such as diversity or the balance between rows with different stopping power. For example, a Continue Watching row near the top of the page may strongly satisfy a user’s immediate intent, but also reduce how much of the page they browse. Modeling these interactions at the page level lets us align the system more directly with user satisfaction than entity-level objectives alone.
  • Better scaling behavior. A generative transformer model gives us a clearer path to improving quality through more data, compute, and model capacity, without repeatedly redesigning the system.
  • Flexibility and extensibility. The prompt-response paradigm is flexible by design. By simplifying feature engineering and enabling whole-page optimization, GenPage makes it easier to support new product experiences, such as additional content types like live events, games, and podcasts; layouts beyond the current two-dimensional structure; personalized UI components; and per-entity artwork personalization, all with fewer architectural changes.

Bringing GenPage into production at Netflix also required solving challenges specific to industry-scale recommender systems. Because the homepage is generated in real time, serving latency is a primary engineering constraint. We also need to handle entity cold start in a constantly evolving catalog, keep the model fresh as user interests and cultural trends shift, and enforce complex product and business rules on the generated output.

Despite these challenges, GenPage has already had substantial production impact. In an online A/B test against a mature, highly optimized multi-stage production recommender, GenPage delivered statistically significant gains on the core user engagement metric we use for launch decisions, while reducing end-to-end serving latency by 20%.

Offline, two findings stood out. First, enriching the prompt helped more than scaling model capacity in our current regime. Second, RL post-training increased homepage diversity even though diversity was not part of the objective.

We expect this approach to generalize to many personalization settings. In this post, we focus on Netflix homepage construction as a concrete case study, sharing our design, trade-offs, and lessons learned.

Data

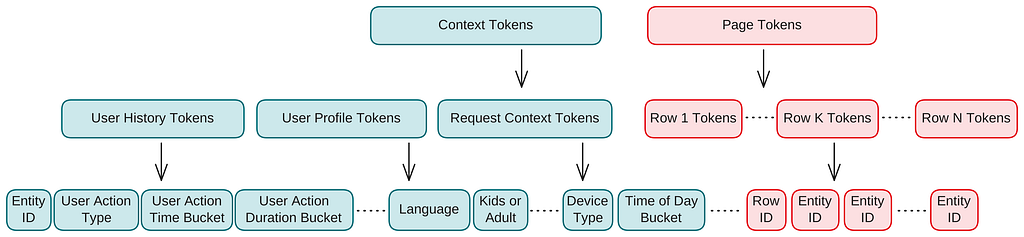
Moving from a traditional recommender to a generative transformer requires us to rethink how the data is represented. Similar to how an LLM turns text into tokens, GenPage represents both the user context and the generated homepage as one sequence of discrete tokens (Figure 2). This sequence includes the full structured homepage layout, with multiple rows and the entities inside them, so the model can generate the page holistically rather than scoring each row or entity in isolation.

Figure 2. Tokenization of Netflix homepage construction data. The context tokens function as the prompt, drawing from diverse data sources including user history, profile attributes, and request context, with example tokens shown for each source. The page tokens represent the generated response, encoding the structured layout of rows and entities.

Each training example represents a homepage impression and consists of three components:

  • Context: user engagement history, profile attributes, and request context.
  • Page: the recommended rows and entities shown on the homepage, in layout order.
  • Feedback: user interactions with that page, such as play, thumbs-up, or abandonment for entities on the page.

Only the context and page are tokenized as model inputs and outputs. Feedback is used to derive supervision signals via our internal reward system (see the Reward system section).

Instead of using an off-the-shelf text tokenizer, we build a domain-specific tokenizer for the homepage construction data. This is a proven approach in recommender systems and other specialized domains including computer vision, biology, and chemistry, where the raw data is not naturally represented as text. Compared with generic text tokenization, this gives us two key advantages:

  • Computational efficiency. Custom tokenization significantly reduces sequence length, lowering inference cost and latency. For example, representing the event “User watched Orange Is the New Black for 50 minutes 30 days ago.” would require 16 tokens with the GPT-5 tokenizer, whereas our scheme compresses it to 4 tokens: [Entity_ID], [Action_Type], [Action_Time_Bucket], and [Action_Duration_Bucket].
  • Product control. A direct mapping between tokens and product concepts, such as rows and entities, makes it easier to control what the model can generate. This is crucial for enforcing business rules on the final homepage.

Context tokens

Context tokens encode user engagement history, user profile, and request context.

We represent user history as a sequence of user actions. For each action, we extract key metadata, including the action type, entity ID, timestamp, and duration. These actions include both explicit signals, such as play, add to My List, and thumbs-up, and implicit signals, such as trailer views or visits to a details page.

User profile tokens capture attributes such as language and profile type. Request context tokens encode signals like time of day, day of week, and device.

Some data sources are too long to include directly as raw token sequences. A user’s full impression history, for example, would be prohibitively expensive to represent in full. In these cases, we use a summarized version. This is a pragmatic trade-off: while GenPage aims to operate on raw inputs as much as possible, handcrafted summaries still introduce a form of prompt engineering into the pipeline. Learning to compress these long data sources end to end is an important direction for future work.

To help the model distinguish between data sources, we insert special tokens that mark the start of each segment. Continuous signals, such as timestamps and durations, are bucketized into discrete ranges to keep the vocabulary finite.

Page tokens

Each entity, such as a show, movie, or game, and each row, such as Korean TV Shows, is represented as a single token. The homepage is serialized in layout order: left to right, then top to bottom. We update the entity and row vocabulary daily to incorporate newly added entities and rows. Entities that are still out of vocabulary at serving time are handled through semantic embedding fusion and fallback tokens, both described later.

In principle, the same paradigm can extend to any output that can be expressed as a linear token sequence. This includes layouts beyond the current two-dimensional structure, such as one-dimensional feeds or mixed layouts, as well as personalized UI components and per-entity outputs such as personalized artwork. We leave these extensions to future work.

Paginated recommendation

To make recommendations responsive to in-session user preferences, the homepage is often generated incrementally, a few rows at a time. Before each pagination request, we append the page tokens from previously generated rows to the prompt, along with the user’s latest engagements on those rows from Netflix’s real-time event-logging infrastructure. This allows the model to generate the next set of recommendations using both the user’s long-term preferences and their most recent in-session behavior.

Reward system

To quantify the long-term value of a recommendation, we rely on an internal reward system described in prior work. The reward system is tuned through online A/B testing to align with long-term user satisfaction and serves as the primary supervision signal for both supervised and reinforcement learning.

The reward system processes user feedback and assigns a scalar reward for every impressed entity on the homepage. For instance, a TV show binge-watched in one night reflects stronger user satisfaction and receives a higher reward than a movie watched for only 10 minutes. An impressed entity that the user abandons receives a negative reward.

We define the page-level reward as the sum of rewards across all impressed entities on the homepage.

Model architecture

GenPage uses a standard decoder-only transformer architecture, the same general architecture behind many modern LLMs. This choice keeps the model simple and flexible, while also letting us benefit from the broad ecosystem of tooling around transformer training and serving.

One architectural detail is that we untie the input embedding and output projection weights. This is useful because pretraining and post-training place different demands on the logits. Next-token prediction pretraining optimizes a softmax over the vocabulary, while weighted binary classification (WBC) post-training optimizes per-token sigmoid scores, as described below. Untying the weights gives the model more flexibility to adapt to both objectives.

Training recipe

Our training pipeline mirrors the LLM recipe: we first teach the model the “language” of the Netflix homepage through pretraining, then align its outputs with user satisfaction through post-training. For post-training, we explore two alternative approaches: weighted binary classification (WBC) and reinforcement learning (RL).

WBC is simpler to optimize and aligns directly with the entity-level objectives of our production ranking models. RL is harder to evaluate and optimize, but it is the key path to GenPage’s full vision of page-level optimization, with the flexibility to incorporate test-time reasoning and multi-token entity representations.

Pretraining via next-token prediction

We pretrain the model with a standard next-token prediction objective: given the context tokens and a prefix of page tokens, the model learns to predict the next page token. This stage focuses on representation learning, teaching the model the relationship between user contexts and successful homepages. Note that our context-page training examples resemble the prompt-response pairs used in LLM supervised fine-tuning (SFT) more than the raw text used in LLM pretraining. We nonetheless call this stage pretraining because we train the model from scratch rather than fine-tuning from an existing checkpoint.

Unlike LLMs, which often face a scarcity of high-quality labeled data, recommender systems have an abundance of user feedback. For pretraining, we use homepage impressions that received positive feedback when served in production, bootstrapping the model to generate pages similar to those produced by the existing production system.

However, pretraining mainly teaches GenPage to imitate the production system. It does not directly optimize the magnitude of the reward, and as GenPage becomes part of production, repeatedly training on pages generated by earlier versions of the model can risk model degeneration. To address these limitations, we explore two post-training approaches.

Post-training via weighted binary classification

One effective way to align the generative model with user satisfaction is weighted binary classification (WBC). At a high level, WBC turns generation into token-level value prediction: given the user context and the tokens generated so far, the model learns to estimate the value of generating each possible next row or entity token.

This objective is easier to optimize than page-level RL. By decomposing the homepage into per-token targets, WBC provides token-level credit assignment by construction, rather than requiring RL to infer how each generated decision contributed to the final page-level reward.

This training setup is enabled by our custom tokenization. Each page token corresponds directly to a specific entity or row, making it straightforward to assign a reward. For every impressed entity on the page, our reward system provides a scalar reward based on user feedback. For each impressed row, we derive a row-level reward by aggregating the rewards of the entities in that row.

From each reward, we derive a binary label from its sign, such as positive engagement versus abandonment, and a weight from its magnitude, such as binge-watching receiving a higher weight than a short play. We then optimize a weighted binary cross-entropy loss on the logit for the corresponding token. Under this setup, the logit for a token can be interpreted as the model’s value estimate for generating that token at that position.

Although the model is trained as a value predictor, it can still generate pages autoregressively. At each step, the model scores the candidate next tokens, greedily selects the token with the highest value, and appends it to the prefix. This process repeats token by token until the full homepage is generated.

Post-training via reinforcement learning

Our second post-training approach is reinforcement learning (RL). WBC is effective for optimizing entity-level metrics, but it does not directly optimize the homepage as a whole. RL treats page generation as a sequential decision-making problem, allowing the model to optimize a page-level reward while preserving the flexibility of autoregressive generation.

This opens the door to several important capabilities:

  • Whole-page optimization. RL directly optimizes an aggregate page-level reward, allowing the model to account for interactions across rows and entities, such as diversity, stopping power, and page-level business constraints.
  • Test-time reasoning. Analogous to its application in LLMs, RL can optimize reasoning capabilities for generative recommendation. Reasoning outputs can also be viewed as a form of automated feature engineering.
  • Multi-token entity support. In our current tokenization, each entity and row is represented as a single token, so rewards map cleanly to individual tokens. In more complex settings, however, an entity may require multiple tokens, such as [Show_ID] plus [Episode_#] for an episode, or a sequence of semantic ID tokens. In that case, WBC’s per-token labeling becomes ambiguous because a single entity-level reward must be distributed across multiple tokens. RL avoids this issue by optimizing the sequence-level return, making it a more natural fit for variable-length, multi-token entities.

Inspired by the RLHF recipe used to align large language models, we adopt a two-step approach. First, we train a reward model that predicts the page-level reward for a generated page. This reward model is distinct from the reward system described earlier. The reward system converts observed user feedback into a scalar reward for a page that was actually shown, whereas the reward model predicts the page-level reward for a generated page without showing it to the user. This prediction is what lets RL optimize against arbitrary candidate pages during training.

Training against a reward model avoids the high variance of off-policy correction on logged or predicted propensities, but introduces the risk of reward hacking. Since the reward model is trained on data generated from the production policy, it is most reliable on pages similar to those the production policy generates. We therefore use a KL penalty to keep the policy close to the pretrained checkpoint, which itself was trained to mimic the production policy. This keeps the pages within the reward model’s region of coverage and limits opportunities for reward hacking.

For the RL algorithm, we adopt Dr. GRPO, a variant of GRPO that mitigates biases in the training objective. To train the model within this framework, we need the following components:

  • Prompts: production user requests, represented by context tokens.
  • Policy and reference models: both are initialized from the pretrained checkpoint; the reference model anchors the KL penalty discussed above.
  • Reward model: a dedicated transformer-based reward model, also initialized from the pretrained checkpoint, predicts the page-level outcome reward, using the sum of entity-level rewards from our internal reward system as the supervision target. We also incorporate rule-based format rewards to guide the RL policy. For example, the page should resemble a list of rows, and business-critical rows or entities should not appear too low on the page.

Addressing production challenges

Cold start

New entities lack the rich interaction data needed to learn robust token embeddings. We address this through two complementary strategies:

  • Context injection. We inject metadata about new or time-sensitive entities (e.g., Live Now events) directly into the context tokens, providing the model with semantic and time-sensitive information.
  • Semantic embedding fusion. Rather than relying solely on entity ID embeddings learned from user interaction data, we represent each entity as a fusion of its ID embedding and a content-based embedding derived from semantic information such as synopses, cast, transcripts, genres, and video content. This fused embedding serves as the input embedding for the entity’s token in the transformer. During training, with small probability, we randomly replace an entity ID token with the generic fallback token (described below), so the model learns to make recommendations from the content-based embedding alone. This ensures that a new entity has a meaningful representation in the same latent space as established entities as soon as its content metadata is available — even before it has any interaction data.

Multi-cadence incremental training

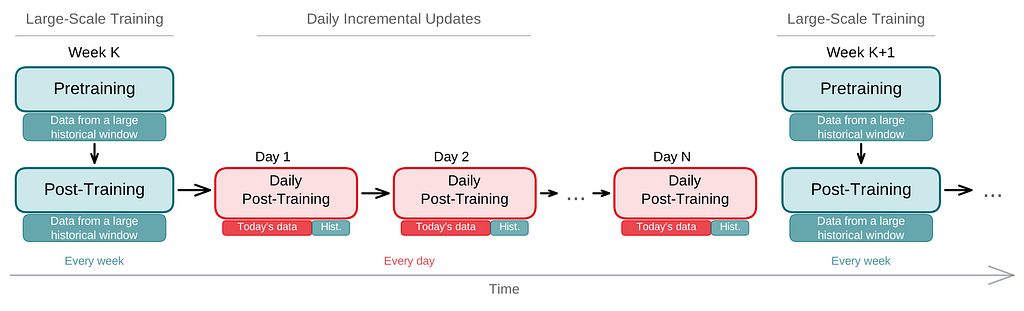
At Netflix scale, daily retraining of a large transformer from scratch is prohibitively expensive, but recommendation models must remain fresh to capture shifting trends and new catalog additions. We address this with a multi-cadence incremental training strategy (Figure 3).

Figure 3. Multi-cadence incremental training. Periodic large-scale pretraining and post-training passes run on a broad historical window. Between them, daily incremental updates combine the latest day’s data with a sampled subset of past data to keep the model fresh while avoiding catastrophic forgetting.

Our training pipeline operates on a cyclic schedule with two distinct rhythms. At a tunable cadence, we conduct a large-scale pretraining and post-training pass on data from a broad historical window. Between these passes, each day we perform an incremental update by continuing post-training from the previous day’s checkpoint, using a mix of the latest day’s data and a sampled subset of past data. This helps the model stay current with new trends and catalog changes while preventing overfitting and catastrophic forgetting.

To manage the daily influx of new tokens (e.g., new entities, rows), we employ fallback tokens. New tokens are initialized using fallback tokens of their type (e.g., [Row_Fallback_Token] for new rows, [Entity_Fallback_Token] for new entities). During training, we randomly replace a small percentage of known tokens with fallback tokens, teaching the model to handle unknown tokens gracefully.

Enforcing business rules

A Netflix homepage must satisfy structural constraints (e.g., organized as a list of rows) as well as product logic such as deduplication, row pinning, and category consistency (e.g., entities in a Comedy row must be comedies). While training signals can encourage rule adherence, they cannot guarantee strict compliance.

We enforce these rules at inference time through constrained decoding. At each autoregressive generation step, we compute a mask of eligible tokens based on the applicable business rules and apply it to the output logits, allowing only rule-compliant tokens to be generated. This is greatly simplified by our custom tokenization: because each entity and row is a single token, business rules map directly to token-level masks, avoiding the multi-token bookkeeping that constrained decoding requires over a text vocabulary. For example, to pin a specific row (e.g., popular games) at a fixed position (e.g., row position 2), we simply mask out all other tokens at that position.

Hybrid row decoding

Autoregressive generation ensures that each newly generated token is conditioned on the full preceding context, but generating every entity token one at a time can be expensive. We leverage the structure of the homepage to balance inference efficiency with the amount of contextual information available to each generated token.

Within each row, the first few entities are especially important: they receive the most user attention and strongly shape the row’s perceived quality and theme. To reduce inference latency, we use a hybrid row decoding strategy. The model autoregressively generates only the first few entities in each row. Conditioned on this generated prefix, we obtain logits for all eligible entities in a single forward pass and select the top-scoring remaining entities, subject to the same inference-time business-rule constraints described above.

This approach preserves autoregressive conditioning where it matters most while avoiding the latency and cost of decoding long rows token by token.

Offline experiments

We ran a series of ablations on Netflix internal data to understand how different components of GenPage affect model quality. Because the system was developed iteratively, individual ablations span different training configurations and data snapshots, so we report only relative comparisons within each study. Unless otherwise noted, experiments use ~200M-parameter models and report results on a held-out evaluation set.

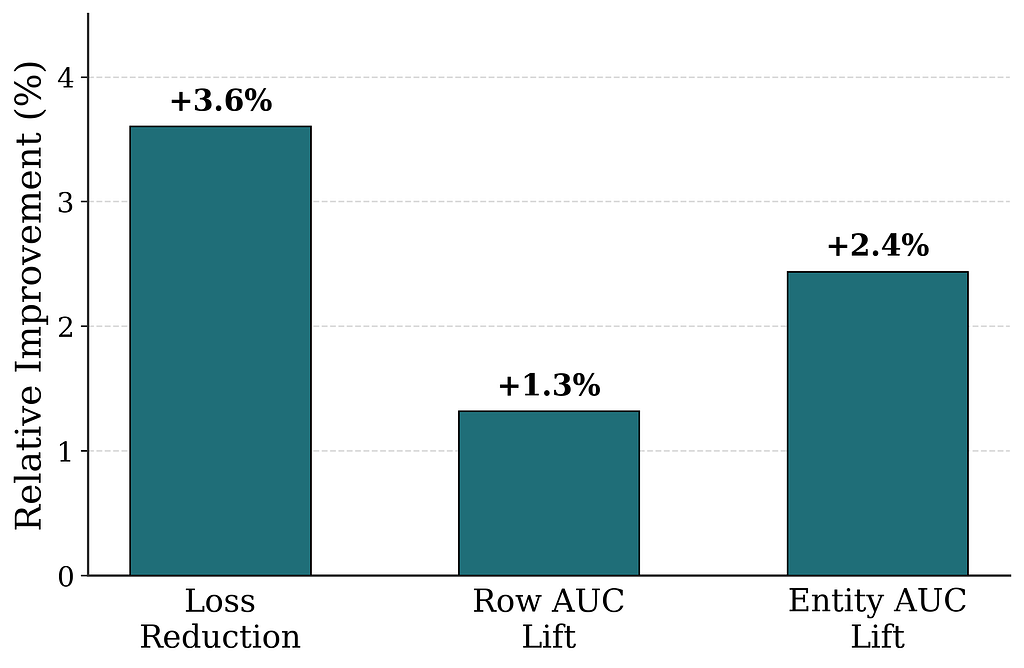
Does pretraining help?

We compare WBC post-training with and without a preceding next-token-prediction pretraining stage. Figure 4 shows that pretraining yields substantial improvements across all metrics.

Figure 4. Relative improvement from pretraining (versus WBC post-training without a pretraining stage), across loss reduction, row AUC lift, and entity AUC lift. Loss is the weighted binary cross-entropy; Row and Entity AUC are sample-weighted ROC-AUC over row and entity targets.

The gains may look small in absolute terms, but they are large in our production regime: setting aside the sample weighting, an Entity AUC lift from 0.91 to 0.92 means that for a randomly drawn pair of impressed entities, the model’s misranking rate drops from 9% to 8% — a magnitude of improvement we rarely observe from a single change on a mature production system. Pretraining the model on the “language” of the Netflix homepage provides a strong initialization for post-training, mirroring the pretrain-then-post-train recipe behind modern LLMs.

How does performance scale with model size?

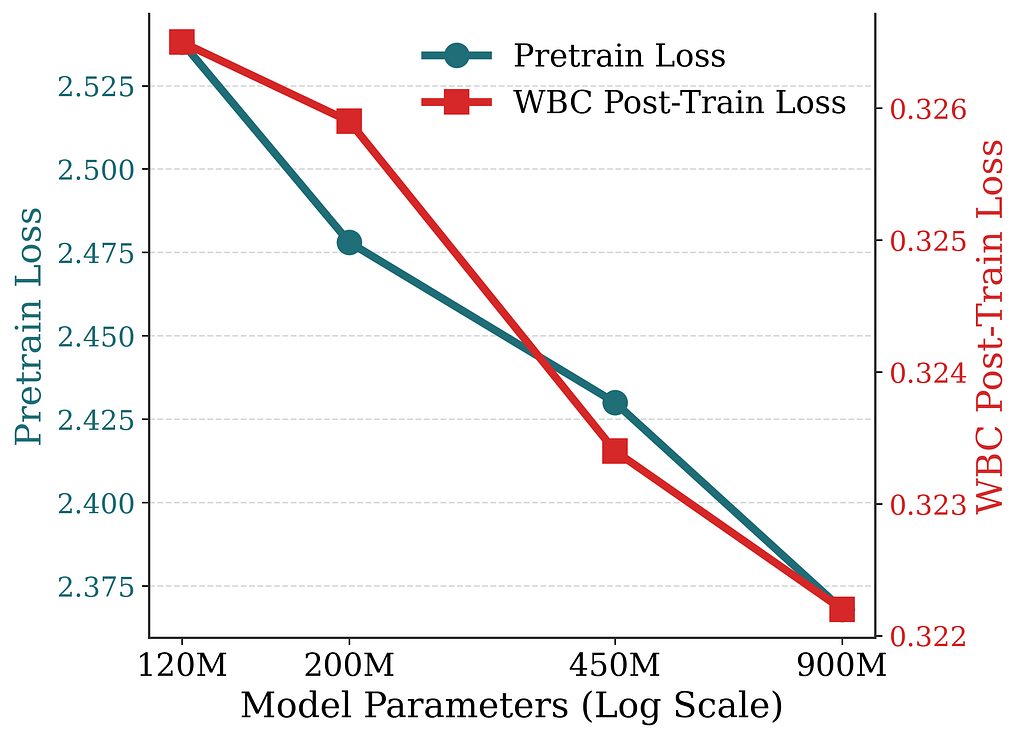
We sweep model size from ~120M to ~900M parameters (Figure 5) and report the next-token-prediction loss from pretraining and the WBC loss from post-training. Both losses decrease in a power-law-like fashion, mirroring the scaling trends seen in LLMs. This confirms that the generative approach scales favorably with model size, suggesting that recommendation quality can be further improved by scaling capacity.

Figure 5. Pretraining and WBC post-training losses as model size scales from 120M to 900M parameters. Both decrease in a power-law-like fashion, mirroring LLM scaling trends.

How does performance scale with information in the user context?

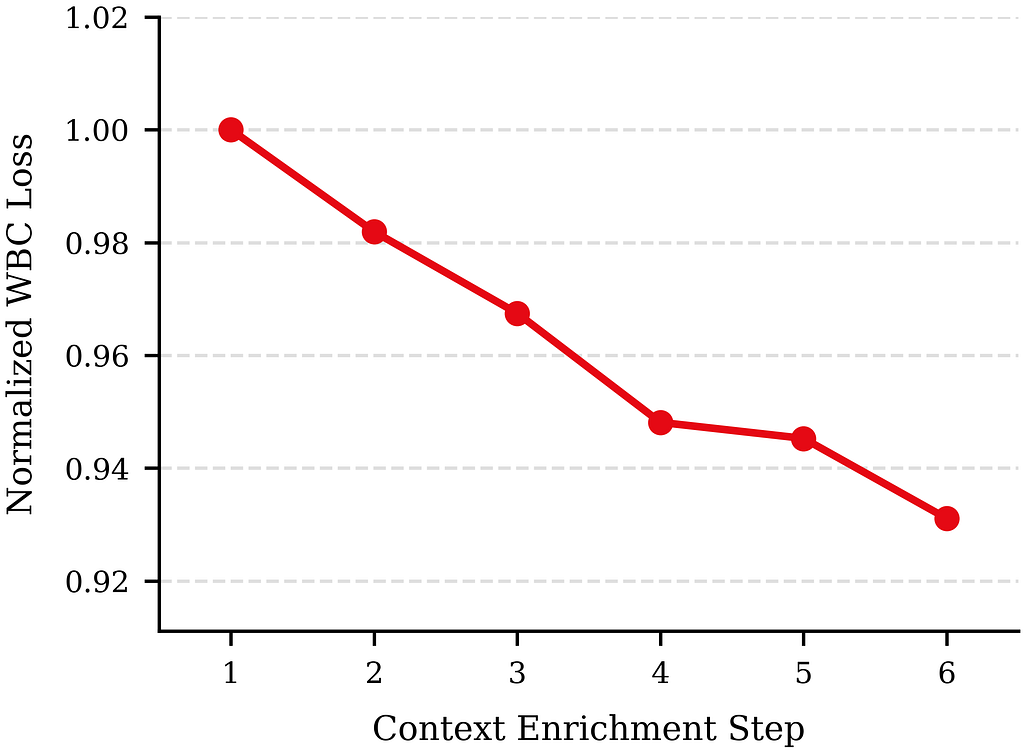
Over the course of development, we progressively enriched the prompt, both by adding new data sources to the context and by refining how each source is tokenized. With model size held fixed, the WBC post-training loss decreases substantially as the context is enriched (Figure 6).

Figure 6. WBC post-training loss as we progressively enrich the user context tokens. Loss is normalized to the first step (= 1.0).

The model-size sweep and the context-enrichment sweep span different axes and are not strictly comparable: the model-size study covers roughly an order of magnitude in parameters, while the context study spans the full trajectory of our prompt design. Even so, the gap between the two is striking. Scaling the model from 120M to 900M parameters reduces WBC loss by roughly 1.3%, whereas the cumulative effect of enriching the context is around 6.9%. In several cases, a single well-designed context addition delivers a larger improvement than the entire ~7.5× model-capacity scaling.

This suggests that, in our regime, enriching the prompt — both what we put in the context and how we tokenize it — yields a substantially larger improvement than scaling model capacity. Personalization quality appears to be bottlenecked first by the information and representation available to the model, and only then by capacity. We expect context enrichment to dominate until the context is saturated, at which point model capacity becomes the primary driver.

Does RL post-training optimize at the page level?

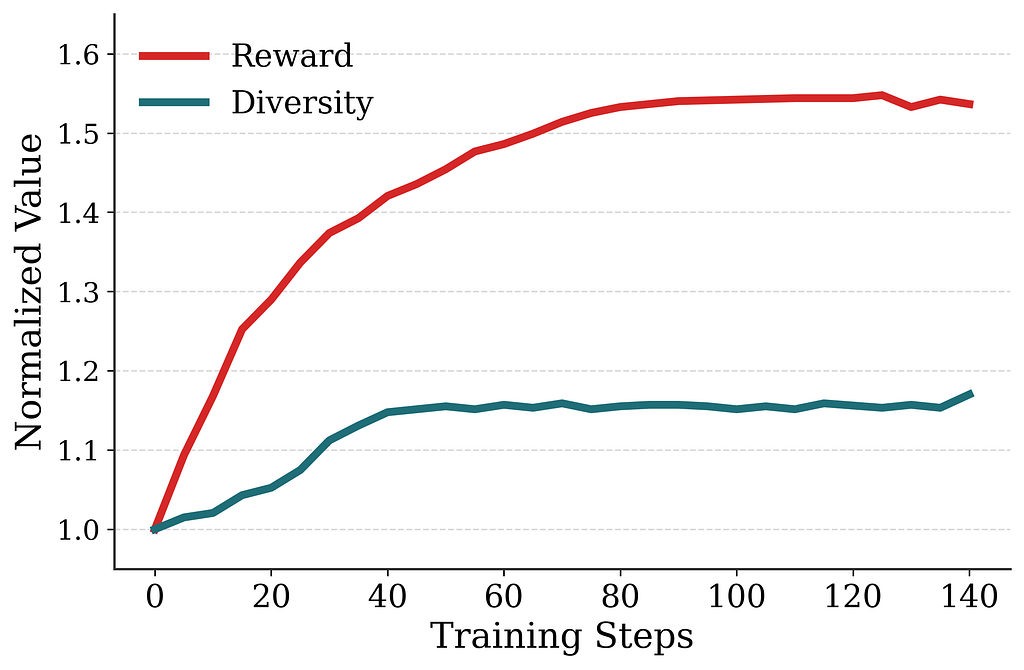
In offline evaluations (Figure 7), RL post-training consistently improves the page-level reward over the pretrained checkpoint, but this is largely confirmatory: the reward is computed using the same model the policy is optimizing against. More interestingly, although diversity is not part of the RL objective, homepage diversity — measured via pairwise embedding distance among entities on the page — also increases over the course of training. This suggests that the RL-trained policy is optimizing the page as a whole rather than myopically optimizing each token in isolation.

Figure 7. RL post-training dynamics. Reward and diversity are shown relative to the initial checkpoint (1.0). Reward rises as expected; diversity also rises, despite not being part of the RL objective.

Online evaluation

We conducted an online A/B test against the current production homepage recommender using GenPage. In this test, GenPage decoded over the existing production row and entity candidate sets, which help handle many business rules (such as eligibility).

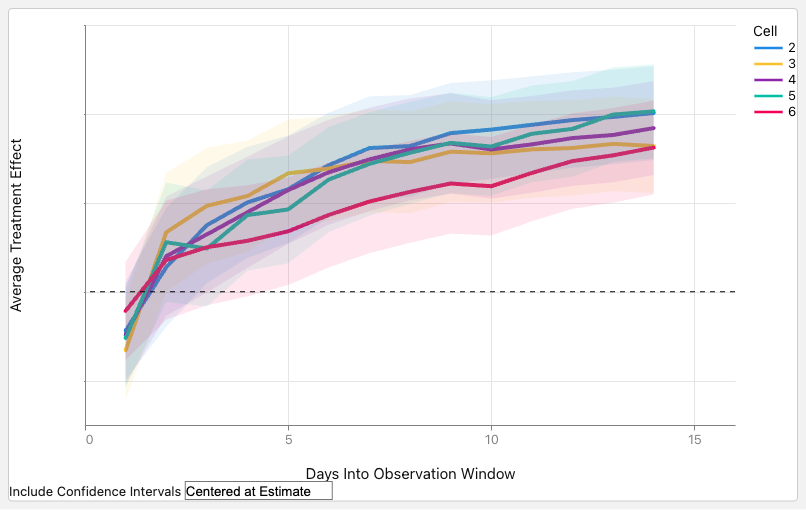
Figure 8 shows the result: all variants delivered statistically significant improvements on the core user engagement metric we use for launch decisions (p < 0.001) against a mature, highly optimized multi-stage production baseline. The variants differed in their training-data configurations; that they all delivered comparable lifts suggests the gain is robust to these design choices rather than dependent on a particular configuration.

Figure 8. Daily core user engagement metric over a 14-day online A/B test. The figure shows the average treatment effect of several GenPage variants (differing in training-data configurations) against the production baseline. Shaded regions are 95% confidence intervals. All variants delivered statistically significant improvements over production.

Alongside the engagement wins, we observed unintended shifts in the distribution of impressed entity categories (e.g., new vs. established titles, TV shows vs. movies). These shifts are not necessarily negative, but they are not something we explicitly optimized for, and they warrant deeper investigation. We suspect these shifts reflect GenPage personalizing more precisely than the production stack — consistent with an increase in homepage impression efficiency, i.e., users engaging with what they saw using fewer impressions. This sharper personalization appears to surface production-inherited components (such as the reward system) that aren’t yet aligned with the new generative paradigm. We plan to characterize the drivers of these shifts and, where appropriate, tune these components so the resulting distributions better align with desired product behavior.

We also observed strong responsiveness to in-session signals: the latest in-session actions quickly influenced subsequent recommendations and faded back to long-term preferences after a day or two, confirming that the model effectively attends to action timestamps. This responsiveness emerges naturally from the generative formulation, without the extensive manual feature engineering used in our production stack.

Contrary to the common assumption that generative models are slower, GenPage reduced end-to-end serving latency by 20% relative to the baseline. By replacing multiple ranking stages and heavy feature computation with a single transformer operating on raw tokenized inputs, we eliminated substantial serving complexity and computational overhead. Custom tokenization and hybrid row decoding further reduced the number of decoding steps, and thus latency. The 20% reduction was achieved without exhausting the available optimizations; further reductions are possible, and this headroom can be reinvested in capacity or richer prompts.

Conclusion

We presented GenPage, an early step toward end-to-end generative Netflix homepage construction: representing user context as a tokenized prompt and generating the entire homepage autoregressively in real time. This collapses the traditional multi-stage recommender stack into a single transformer that can be optimized end-to-end.

In online A/B tests against a mature, highly optimized multi-stage production system, GenPage delivered statistically significant gains on the core user engagement metric we use for launch decisions, while reducing end-to-end serving latency by 20%. Achieving this required adapting the LLM training recipe — pretraining followed by WBC or RL post-training — together with a set of domain-specific techniques: custom tokenization for serving efficiency and product control, context injection and semantic embedding fusion for entity cold start, multi-cadence incremental training for model freshness, constrained decoding for business-rule enforcement, and hybrid row decoding for inference efficiency.

Two offline findings stand out. First, in our current regime, enriching the prompt yields a substantially larger improvement than scaling model capacity — a takeaway we expect to generalize to other industry-scale personalization settings, at least until the available context is fully exploited. Second, RL post-training increases homepage diversity even though diversity is not part of the objective — an indication that page-level optimization captures interactions across rows and entities.

Several pieces of the full vision are still in progress: long context still relies on handcrafted summarization, and broader LLM-style capabilities — language, multimodality, and reasoning — have not yet been incorporated. One promising direction here is a hybrid tokenization combining our domain-specific tokens with generic text tokens, retaining structured control while inheriting the strengths of general-purpose LLMs; conceptually, this introduces an additional recommendation modality into an LLM.

More broadly, we expect many advances from the LLM ecosystem to transfer naturally to this setting, and the boundary between an LLM and a recommender system may increasingly blur. Our results suggest this is a viable path toward simpler recommender systems that align more directly with user satisfaction.

Acknowledgments

Contributors to this work (in alphabetical order): Abhishek Agrawal, Baolin Li, Casey Stella, Daneo Zhang, Dan Zheng, Donnie DeBoer, Fengdi Che, Fernando Amat Gil, Grace Huang, Inbar Naor, Ishita Verma, Jason Uh, Jimmy Patel, Justin Basilico, Lanxi Huang, Lingyi Liu, Liping Peng, Louis Wang, Michelle Kislak, Nathan Kallus, Nicolas Hortiguera, Paran Jain, Qusai Al-Rabadi, Rein Houthooft, Ryan Lee, Santino Ramos, Scarlet Chen, Shaojing Li, Sheallika Singh, Si Cheng, Wei Wang, and ZQ Zhang.


GenPage: Towards End-to-End Generative Homepage Construction at Netflix was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.
Post-Training Generative Recommenders with Advantage-Weighted Supervised Finetuning

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/post-training-generative-recommenders-with-advantage-weighted-supervised-finetuning-61a538d717a9

Author: Keertana Chidambaram, Qiuling Xu, Ko-Jen Hsiao, Moumita Bhattacharya

(*The work was done when Keertana interned at Netflix.)

Introduction

This blog focuses on post-training generative recommender systems. Generative recommenders (GRs) represent a new paradigm in the field of recommendation systems (e.g. HSTU, OneRec). These models draw inspiration from recent advancements in transformer architectures used for language and vision tasks. They approach the recommendation problem, including both ranking and retrieval, as a sequential transduction task. This perspective enables generative training, where the model learns by imitating the next event in a sequence of user activities, thereby effectively modeling user behavior over time.

However, a key challenge with simply replicating observed user patterns is that it may not always lead to the best possible recommendations. User interactions are influenced by a variety of factors — such as trends, or external suggestions — and the system’s view of these interactions is inherently limited. For example, if a user tries a popular show but later indicates it wasn’t a good fit, a model that only imitates this behavior might continue to recommend similar content, missing the chance to enhance the user’s experience.

This highlights the importance of incorporating user preferences and feedback, rather than solely relying on observed behavior, to improve recommendation quality. In the context of recommendation systems, we benefit from a wealth of user feedback, which includes explicit signals such as ratings and reviews, as well as implicit signals like watch time, click-through rates, and overall engagement. This abundance of feedback serves as a valuable resource for improving model performance.

Given the recent success of reinforcement learning techniques in post-training large language models, such as DPO and GRPO, this study investigates whether similar methods can be applied to generative recommenders. Ultimately, our goal is to identify both the opportunities and challenges in using these techniques to enhance the quality and relevance of recommendations.

Unlike language models, post-training generative recommenders presents unique challenges. One of the most significant is the difficulty of obtaining counterfactual feedback in recommendation scenarios. The recommendation feedback is generated on-policy — that is, it reflects users’ real-time interactions with the system as they naturally use it. Since a typical user sequence can span weeks or even years of activity, it is impractical to ask users to review or provide feedback on hypothetical, counterfactual experiences. As a result, the absence of counterfactual data makes it challenging to apply post-training methods such as PPO or DPO, which require feedback from counterfactual user sequences.

Furthermore, post-training methods typically rely on a reward model — either implicit or explicit — to guide optimization. The quality of reward models heavily influences the effectiveness of post-training. In the context of recommendation systems, however, reward signals tend to be much noisier. For instance, if we use watch time as an implicit reward, it may not always accurately reflect user satisfaction: a viewer might stop watching a favorite show simply due to time constraints, while finishing a lengthy show doesn’t necessarily indicate genuine enjoyment.

To address these post-training challenges, we introduce a novel algorithm called Advantage-Weighted Supervised Fine-tuning (A-SFT). Our analysis first demonstrates that reward models in recommendation systems often exhibit higher uncertainty due to the issues discussed above. Rather than relying solely on these uncertain reward models, A-SFT combines supervised fine-tuning with the advantage function to more effectively guide post-training optimization. This approach proves especially effective when the reward model has high variance but still provides valuable directional signals. We benchmark A-SFT against four other representative methods, and our results show that A-SFT achieves better alignment between the pre-trained generative recommendation model and the reward model.

In Figure 1, we conceptualize the pros and cons of different post-training paradigms. For example, Online Reinforcement Learning is most useful when the reward model has a good generalization ability, and behavior cloning is suitable when no reward models are available. Using these algorithms under fitting use cases is the key to a successful post-training. For example, over-exploitation of noisy reward models will hurt task performance, as guidance from the reward models can be simply noise. Conversely, not leveraging a good reward model leaves out potential improvements. We find A-SFT fits the sweet point between offline reinforcement learning and behavior cloning, where it benefits from the directional signals in those noisy estimations and is less dependent on the reward accuracy.

Figure 1: The landscape of RL algorithms based on the reward models’ accuracy

Challenges in Post-training for Recommendation

Reinforcement Learning from Human Feedback (RLHF) is the most popular framework for post-training large language models. In this framework, human annotators evaluate and rank different outputs generated by a model. This feedback is then used to train a reward model that predicts how well a model output aligns with human preferences. This reward model then serves as a proxy for human judgment during reinforcement learning, guiding the model to generate outputs that are more likely to be preferred by humans.

While traditional RLHF methods like PPO or DPO are effective for aligning LLMs, there are several challenges in applying them directly to large-scale recommendation systems:

  1. Lack of Counter-factual Observations

As in typical RLHF settings, collecting real-time feedback from a diverse user base across a wide range of items is both costly and impractical. The data in recommendation are generated by the real-time user interests. Any third-party annotators or even the user themselves lack the practical means to evaluate an alternative reality. For example, it is impractical to ask the Netflix users to evaluate hundreds of unseen movies. Consequently, we lack a live environment in which to perform reinforcement learning.

2. Noisy Reward Models

In addition to the limited counter-factual data, the recommendation task itself has a higher randomness by its nature. The recommendation data has less structure than language data. Users choose to watch some shows not because there is a grammar rule that nouns need to follow by the verbs. In fact, the users’ choices usually exhibit a level of permutation invariance, where swapping the order of events in the user history still makes a valid activity sequence. This randomness in the behaviors makes learning a good reward model extremely difficult. Often the reward models we learnt still have a large margin of errors.

Here is an ablation study we did on the reward model performance with O(Millions) users and O(Billions) of tokens. The reward model uses an open-sourced HSTU architecture in the convenience of reproducing this study. We adopt the standard RLHF approach of training a reward model using offline, human-collected feedback. We start by creating a proxy reward, scored on a scale from 1 to 5 in the convenience of understanding. This reward model is co-trained as a shallow reward head on top of the generative recommender. It predicts the reward for the most recently selected title based on a user’s interaction history. To evaluate its effectiveness, we compare the model’s performance against two simple baselines: (1) predicting the next reward as the average reward the user has given in their past interactions, and (2) predicting it as the average reward that all users have assigned to that particular title in previous interactions.

Table 1: Reward model performance metrics

We observe that the model’s predictions do not significantly outperform the simple baselines. This result is intuitive, as a user’s historical interactions typically cover only a small subset of titles, making it difficult to accurately predict their responses to the vast number of unexplored titles in the catalogue. We expect this to be a potential issue for any large recommendation systems where the ratio between explored and unexplored titles is very small.

3. Lack of Logged Policy

In recommendation systems, the policy that generated the logged data is typically unknown and cannot be directly estimated. Offline reinforcement learning methods often rely on Inverse Propensity Scoring (IPS) to debias such data by reweighting interactions according to the logging policy’s action probabilities. However, estimating the logging policy accurately is challenging and prone to error, which can introduce additional biases, and IPS itself is known to suffer from high variance. Consequently, offline RL approaches that depend on IPS are ill-suited for our setting.

Advantage Weighted Supervised Fine Tuning

Given the three challenges outlined above, we propose a new algorithm Advantage-Weighted SFT (A-SFT). It leverages a combination of supervised fine-tuning and advantage reweighting from reinforcement learning. The key observation is as follows. Despite the reward estimation for each individual event having a high uncertainty, we find the estimations of rewards contain directional signals between high-reward and low-reward events. These signals could help better align the model during post-training.

A central factor in this study is the generalization ability of the reward model. Better generalization enables more accurate predictions of user preferences for unseen titles, thereby making exploration more effective. For reward models with moderate to high generalization power, both online RL methods such as PPO and offline RL methods such as CQL can perform effectively. However, in our setting, reward model generalization is worse than the language counterparts’, which makes these algorithms less appropriate. In addition, the use of techniques like inverse propensity scoring (IPS) introduces a heightened risk of high-variance estimates, prompting us to exclude algorithms such as off-policy REINFORCE.

Our proposed method A-SFT does not rely on IPS. With no need of prior knowledge of the logging policy, it can be generally applied to cases where observation of the environments are limited or biased. This is particularly useful to the recommendation setting due to the user feedback loop and distribution shifts with time. Without knowing the logging policy, A-SFT still provides means to control the policy deviation between the current policy and logging policy by tuning the parameter. This design provides essential means to control the learnt bias from uncertain reward models. We show that A-SFT outperforms baseline behavior cloning by directly optimizing observed rewards.

The advantage-weighted SFT algorithm is as follows:

For the results presented in this blog post, we treat the recommendation problem as a contextual bandit, i.e. given a history of user interactions as the context, can we recommend a high reward next title recommendation for the user?

Benchmarks

We compared representative algorithms including PPO, IPO, DPO, CQL and SFT as the baselines:

  1. Reward weighted Behavior Cloning: This benchmark algorithm modifies supervised fine-tuning (SFT) by weighting the loss with the raw rewards of the chosen item instead of weighing the loss with advantage as in the proposed algorithm.
  2. Rejection Sampling Direct Preference Optimization / Identity Preference Optimization (RS DPO/IPO): this is a variant of DPO/IPO where, for each user history x, ​we generate contrasting response pairs by training an ensemble of reward models to estimate confidence intervals for the reward of multiple potential responses y. If the lower bound of the reward confidence interval for one response​ is less than the upper bound for another response, then this pair is used to train DPO/IPO.
  3. Conservative Q-Learning (CQL): This is a standard offline algorithm that learns a conservative Q function, penalizing overestimation of Q-values, particularly in regions of the state-action space with little or no reward data.
  4. Proximal Policy Optimization (PPO): This is a standard RLHF (Reinforcement Learning from Human Feedback) algorithm that uses reward models as an online environment. PPO learns an advantage function and optimizes the policy to maximize expected reward while maintaining proximity to the initial policy.

We sampled a separate test set of O(Millions) users. This test set is collected on a future date after the training.

Offline Evaluation Results

We evaluate our algorithm on a dataset of high-reward user trajectories. For sake of simplicity, we consider a trajectory to have a high reward if the accumulated reward is higher than the median of the population. We present the following metrics for the held out test dataset:

  1. NDCG@k: This measures the ranking quality of the recommended items up to position k. It accounts for the position of relevant items in the recommendation list, assigning higher scores when relevant items appear higher in the ranking. The gain is discounted logarithmically at lower ranks, and the result is normalized by the ideal ranking (i.e., the best possible ordering of items).
  2. HR@k: This measures the proportion of test cases in which the ground-truth chosen item y appears in the top k recommendations. It is a binary metric per test case (hit or miss) and is averaged over all test cases.
  3. MRR: MRR evaluates the ranking quality by measuring the reciprocal of the rank at which the chosen item appears in the recommendation list. The metric is averaged across all test cases.
  4. Reward Model as A Judge: We use the reward model to evaluate the policy for future user events. We propose to use an ensemble of reward models for the evaluation to increase confidence. The result is based on the discounted reward generated for a few steps. The standard deviation is less than 4%.

We measure the percentage improvement in each metric compared to the baseline, Reward Weighted Behavior Cloning(BC). We notice that advantage weighted SFT shows the largest improvement in metrics, outweighing BC as well as reward model dependent algorithms like CQL, PPO, DPO and IPO.

Our experiments show that advantage weighted SFT is a simple but promising approach for post-training generative recommenders as it deals with the issue of poor reward model generalizations and lack of IPS. More specifically, we find PPO, IPO and DPO achieve a good reward score, but also causes the overfitting from the reward model. Conservative Q-Learning achieves more robust improvements but does not fully capture the potential signals in the reward modeling. A-SFT achieved both better recommendation metrics and reward scores.


Post-Training Generative Recommenders with Advantage-Weighted Supervised Finetuning was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.
Using generative AI to teach computing: Insights from research

Post Syndicated from Katharine Childs original https://www.raspberrypi.org/blog/using-generative-ai-to-teach-computing-insights-from-research/

As computing technologies continue to rapidly evolve in today’s digital world, computing education is becoming increasingly essential. Arto Hellas and Juho Leinonen, researchers at Aalto University in Finland, are exploring how innovative teaching methods can equip students with the computing skills they need to stay ahead. In particular, they are looking at how generative AI tools can enhance university-level computing education. 

In our monthly seminar in September, Arto and Juho presented their research on using AI tools to provide personalised learning experiences and automated feedback to help requests, as well as their findings on teaching students how to write effective prompts for generative AI systems. While their research focuses primarily on undergraduate students — given that they teach such students — many of their findings have potential relevance for primary and secondary (K-12) computing education. 

Students attend a lecture at a university.

Generative AI consists of algorithms that can generate new content, such as text, code, and images, based on the input received. Ever since large language models (LLMs) such as ChatGPT and Copilot became widely available, there has been a great deal of attention on how to use this technology in computing education. 

Arto and Juho described generative AI as one of the fastest-moving topics they had ever worked on, and explained that they were trying to see past the hype and find meaningful uses of LLMs in their computing courses. They presented three studies in which they used generative AI tools with students in ways that aimed to improve the learning experience. 

Using generative AI tools to create personalised programming exercises

An important strand of computing education research investigates how to engage students by personalising programming problems based on their interests. The first study in Arto and Juho’s research  took place within an online programming course for adult students. It involved developing a tool that used GPT-4 (the latest version of ChatGPT available at that time) to generate exercises with personalised aspects. Students could select a theme (e.g. sports, music, video games), a topic (e.g. a specific word or name), and a difficulty level for each exercise.

A student in a computing classroom.

Arto, Juho, and their students evaluated the personalised exercises that were generated. Arto and Juho used a rubric to evaluate the quality of the exercises and found that they were clear and had the themes and topics that had been requested. Students’ feedback indicated that they found the personalised exercises engaging and useful, and preferred these over randomly generated exercises. 

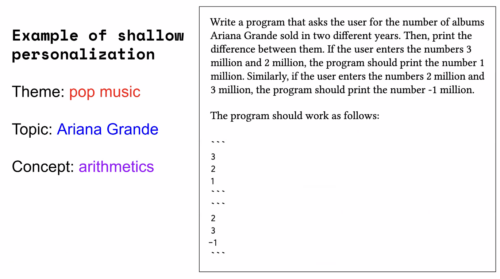
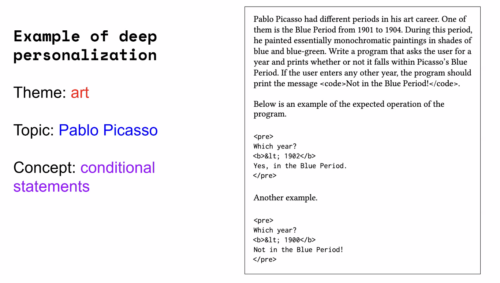
Arto and Juho also evaluated the personalisation and found that exercises were often only shallowly personalised, however. In shallow personalisations, the personalised content was added in only one sentence, whereas in deep personalisations, the personalised content was present throughout the whole problem statement. It should be noted that in the examples taken from the seminar below, the terms ‘shallow’ and ‘deep’ were not being used to make a judgement on the worthiness of the topic itself, but were rather describing whether the personalisation was somewhat tokenistic or more meaningful within the exercise. 

In these examples from the study, the shallow personalisation contains only one sentence to contextualise the problem, while in the deep example the whole problem statement is personalised. 

The findings suggest that this personalised approach may be particularly effective on large university courses, where instructors might struggle to give one-on-one attention to every student. The findings further suggest that generative AI tools can be used to personalise educational content and help ensure that students remain engaged. 

How might all this translate to K-12 settings? Learners in primary and secondary schools often have a wide range of prior knowledge, lived experiences, and abilities. Personalised programming tasks could help diverse groups of learners engage with computing, and give educators a deeper understanding of the themes and topics that are interesting for learners. 

Responding to help requests using large language models

Another key aspect of Alto and Juho’s work is exploring how LLMs can be used to generate responses to students’ requests for help. They conducted a study using an online platform containing programming exercises for students. Every time a student struggled with a particular exercise, they could submit a help request, which went into a queue for a teacher to review, comment on, and return to the student. 

The study aimed to investigate whether an LLM could effectively respond to these help requests and reduce the teachers’ workloads. An important principle was that the LLM should guide the student towards the correct answer rather than provide it. 

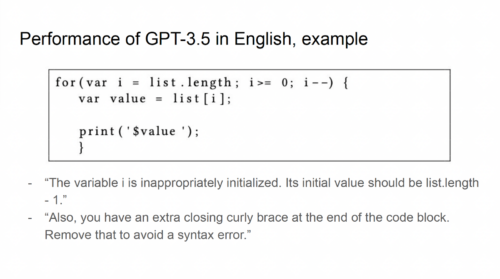
The study used GPT-3.5, which was the newest version at the time. The results found that the LLM was able to analyse and detect logical and syntactical errors in code, but concerningly, the responses from the LLM also addressed some non-existent problems! This is an example of hallucination, where the LLM outputs something false that does not reflect the real data that was inputted into it. 

An example of how an LLM was able to detect a logical error in code, but also hallucinated and provided an unhelpful, false response about a non-existent syntactical error. 

The finding that LLMs often generated both helpful and unhelpful problem-solving strategies suggests that this is not a technology to rely on in the classroom just yet. Arto and Juho intend to track the effectiveness of LLMs as newer versions are released, and explained that GPT-4 seems to detect errors more accurately, but there is no systematic analysis of this yet. 

In primary and secondary computing classes, young learners often face similar challenges to those encountered by university students — for example, the struggle to write error-free code and debug programs. LLMs seemingly have a lot of potential to support young learners in overcoming such challenges, while also being valuable educational tools for teachers without strong computing backgrounds. Instant feedback is critical for young learners who are still developing their computational thinking skills — LLMs can provide such feedback, and could be especially useful for teachers who may lack the resources to give individualised attention to every learner. Again though, further research into LLM-based feedback systems is needed before they can be implemented en-masse in classroom settings in the future. 

Teaching students how to prompt large language models

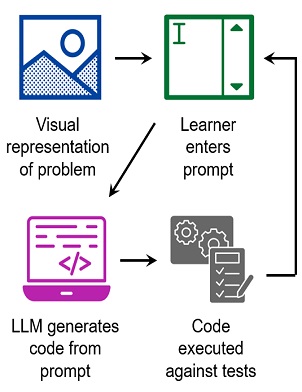
    Finally, Arto and Juho presented a study where they introduced the idea of ‘Prompt Problems’: programming exercises where students learn how to write effective prompts for AI code generators using a tool called Promptly. In a Prompt Problem exercise, students are presented with a visual representation of a problem that illustrates how input values will be transformed to an output. Their task is to devise a prompt (input) that will guide an LLM to generate the code (output) required to solve the problem. Prompt-generated code is evaluated automatically by the Promptly tool, helping students to refine the prompt until it produces code that solves the problem.

    The workflow of a Prompt Problem 

    Feedback from students suggested that using Prompt Problems was a good way for them to gain experience of using new programming concepts and develop their computational thinking skills. However, students were frustrated that bugs in the code had to be fixed by amending the prompt — it was not possible to edit the code directly. 

    How these findings relate to K-12 computing education is still to be explored, but they indicate that Prompt Problems with text-based programming languages could be valuable exercises for older pupils with a solid grasp of foundational programming concepts. 

    Balancing the use of AI tools with fostering a sense of community

    At the end of the presentation, Arto and Juho summarised their work and hypothesised that as society develops more and more AI tools, computing classrooms may lose some of their community aspects. They posed a very important question for all attendees to consider: “How can we foster an active community of learners in the generative AI era?” 

    In our breakout groups and the subsequent whole-group discussion, we began to think about the role of community. Some points raised highlighted the importance of working together to accurately identify and define problems, and sharing ideas about which prompts would work best to accurately solve the problems. 

    As AI technology continues to evolve, its role in education will likely expand. There was general agreement in the question and answer session that keeping a sense of community at the heart of computing classrooms will be important. 

    Arto and Juho asked seminar attendees to think about encouraging a sense of community. 

    Further resources

    The Raspberry Pi Computing Education Research Centre and Faculty of Education at the University of Cambridge have recently published a teacher guide on the use of generative AI tools in education. The guide provides practical guidance for educators who are considering using generative AI tools in their teaching. 

    Join our next seminar

    In our current seminar series, we are exploring how to teach programming with and without AI technology. Join us at our next seminar on Tuesday, 12 November at 17:00–18:30 GMT to hear Nicholas Gardella (University of Virginia) discuss the effects of using tools like GitHub Copilot on the motivation, workload, emotion, and self-efficacy of novice programmers. To sign up and take part in the seminar, click the button below — we’ll then send you information about joining. We hope to see you there.

    The schedule of our upcoming seminars is online. You can catch up on past seminars on our previous seminars and recordings page.

    The post Using generative AI to teach computing: Insights from research appeared first on Raspberry Pi Foundation.

    How to build an enterprise LLM application: Lessons from GitHub Copilot

    Post Syndicated from Shuyin Zhao original https://github.blog/2023-09-06-how-to-build-an-enterprise-llm-application-lessons-from-github-copilot/

    If you want to build and scale an application using a large language model (LLM), this article’s for you.

    It took us three years to develop GitHub Copilot before we officially launched it to the general public. To go from idea to production, we followed three stages—find it, nail it, scale it—loosely based on the “Nail It, Then Scale It” framework for entrepreneurial product development.

    Here’s how it breaks down:

    • Find it: Identify an impactful problem space for your LLM application
    • Nail it: Create a smooth AI product experience
    • Scale it: Get your LLM application ready and useable for general availability (GA)

    Let’s get started.

    Find it: Isolate the problem you want to solve

    Sometimes the hardest part about creating a solution is scoping down a problem space. The problem should be focused enough to quickly deliver impact, but also big enough that the right solution will wow users. Additionally, you want to find a problem where the use of an LLM is the right solution (and isn’t integrated to just drive product engagement).

    • Get clear on who you want to help. We saw that AI could drive efficiency, so we wanted to prioritize helping developers who were consistently crunched for time, enabling them to write code faster with less context switching.

    • Focus on a single problem, first. Rather than trying to address all developer problems with AI, we focused on one part of the software development lifecycle: coding functions in the IDE. At the time, most AI coding assistants could only complete a single line of code.

    • Balance product ambition with quality. While the GitHub Copilot team initially explored generating entire commits, the state of LLMs couldn’t support that function at a high enough quality at the time. Through additional testing, the team landed on code suggestions at the “whole function” level.

    • Meet people where they are. When it comes to designing products for developers, an LLM app should amplify an existing tool or integrate into an existing workflow. A mantra of the GitHub Copilot team was, “It’s a bug if you have to change the way you code when using GitHub Copilot.” In practice, this means enabling developers to receive code suggestions without changing how they work.

    Nail it: Iterate to create a smooth AI product experience

    Product development with emerging tech, like generative AI, is often more of a winding path and a linear journey because so much is unknown and rapid advancements in the field can quickly open new doors. Building quick iteration cycles into the product development process allows teams to fail and learn fast. At GitHub, the main mechanism for us to quickly iterate is an A/B experimental platform.

    According to Idan Gazit, Senior Director of Research for GitHub Next, “We have to design apps not only for models whose outputs need evaluation by humans, but also for humans who are learning how to interact with AI.

    • Put yourself in users’ shoes. GitHub employees have a culture of putting themselves in the shoes of their end users by “dogfooding” products before—and after—they’re released. In practice, this meant the GitHub Copilot team stood up a simple web interface where it could tinker with foundation models and explore ways to leverage those models in their own developer workflows.

      We quickly found that a web interface was not the right canvas since it meant developers had to switch back and forth between their editor and the web browser. As a result, the team decided to focus on bringing GitHub Copilot to the IDE and making the AI capability modeless—or working in the background.

      The developers on our team also noticed they often referenced multiple open tabs in the IDE while coding. This insight led them to experiment with a technique called neighboring tabs, where GitHub Copilot processes multiple files open in a developer’s IDE instead of just the single one the developer is working on. Neighboring tabs helped to increase the acceptance rates of GitHub Copilot’s suggestions by 5%.

    • Evaluate your testing tools. As our experiment continued, we had to scale our internal testing tools to be more versatile and powerful. While we initially relied on our own tools for testing, we ultimately switched to the Microsoft Experimentation Platform to optimize functionality based on the feedback and interaction at scale.

    • Avoid the sunk cost fallacy. This is when you’re reluctant to abandon a course of action because you’ve heavily invested in it—even when it’s clear switching gears would be more beneficial.

      The GitHub and OpenAI teams initially believed every coding language would require its own fine-tuned AI model. But the field of generative AI was rapidly advancing, and our assumption turned out to be incorrect. In the end, OpenAI’s LLMs significantly improved and one model could handle a wide variety of coding languages and tasks.

    • Make a habit of revisiting old ideas. In a field that’s rapidly advancing, the functions that aren’t feasible with today’s LLMs might be possible with tomorrow’s.

      In the beginning, we explored a chat interface for developers to ask coding questions. However, in early testing, users had much higher expectations for the capabilities and quality of coding suggestions than GitHub Copilot could deliver at the time. As a result, we deprioritized the feature. But as customers became familiar with AI chatbot following the emergence of ChatGPT and LLMs continued to evolve, an iterative chat experience, like GitHub Copilot Chat, became possible.

    Scale it: Optimize quality, usability, and responsible use of AI to get to GA

    Early feedback and technical previews are key to driving product improvements and getting your application to GA. Below you’ll find the steps we took before launching the GitHub Copilot technical preview, how we managed the technical preview and optimized user feedback, and how we prepared our internal infrastructure to handle demand at scale.

    Optimize quality and usability

    • Ensure consistent results. Because LMMs are probabilistic—meaning they don’t always produce the same, predictable outcomes—experimentation with them needs to be statistically based. One solution involves setting up a quality pipeline that addresses this unique challenge of building with LLMs.

      For instance, when the GitHub Copilot team first decided to provide whole function coding suggestions, we also had to ensure output predictability and consistency, where the same prompt and context would produce the same suggestions from the AI model.

      To achieve this, the team applied two strategies: changing the parameters to reduce the randomness of outputs and caching responses. Additionally, using cached responses instead of generating new responses to the same prompt not only reduced variability in suggestions, but it also improved performance.

    • Implement a waitlist for your technical preview. A waitlist allowed the GitHub Copilot team to manage questions, feedback, and comments—and ensure we could address them effectively. This approach also helped ensure we had a diverse set of early adopters across developers of varying experience levels to provide feedback.

    • Take advantage of real user feedback. In one example, developers shared that an update had negatively affected the quality of the model’s coding suggestions. In response, the GitHub Copilot team implemented a new guardrail metric—the percentage of suggestions that are multi-line vs. single line—and tuned the model to ensure customers continued to get high-quality suggestions.

      While the GitHub team actively dogfooded GitHub Copilot to understand what the experience was like for developers, we also benefited from developers outside GitHub adding diverse feedback across real-world use cases. The GitHub Copilot team engaged and interacted with technical preview users early, often, and on the users’ preferred platforms. This allowed us to actively respond to issues and feedback in real time.

    • Commit to iterating as you scale. When GitHub Copilot became generally available, the team not only had to improve the product, but also its infrastructure. When we experimented with and quickly iterated GitHub Copilot, it worked directly with the OpenAI API. As the product grew, we scaled our use of Microsoft Azure’s infrastructure to ensure GitHub Copilot had the quality, reliability, and responsible guardrails of a large-scale, enterprise-grade product.

    • Define the product’s key performance metrics. To optimize GitHub Copilot, we used early developer feedback to identify the right performance metrics, such as code acceptance rate and, eventually, code retention rate (which measures how much of the original code suggestion is kept or edited by a developer).

    • Optimize costs. The team worked to optimize the costs of delivering GitHub Copilot suggestions while balancing developer impact. For instance, before we decided on using ghost text—the gray text that flashes one coding suggestion while you type—the tool would eagerly generate 10 suggestions and display them all at once. This incurred upfront compute costs for suggestions two through 10, when most people choose the first one. But it also created a user experience cost, because those 10 suggestions pulled developers out of their workflow and into an evaluation mindset. “It was like paying to calculate the results that appear on the second page of a search engine—and making that second page grab your attention—even though most folks end up using the top result,” Gazit says.

      Optimizing costs is an ongoing project, and we’re exploring new ideas to reduce costs while improving the user experience.

    Optimize responsible use of AI

    • Prioritize security and trust. Feedback during GitHub Copilot’s technical preview reinforced the importance of suggesting code that is secure. In response, the team integrated code security capabilities to filter out suggestions that could contain security vulnerabilities (e.g., SQL injections and hard coded credentials) and used natural language filters from Azure OpenAI Service to filter out offensive content.*

    • Allow your community to help you. At GitHub, we deeply valued our extensive developer community for feedback on our products and collaborating with them to improve our offerings. With GitHub Copilot, our developer community was critical to understanding the potential around AI—and some concerns, too.

      For instance, the developer community was concerned that GitHub Copilot suggestions might match public code. In response, the GitHub Copilot team created a filter to block suggestions matching public source code in GitHub public repositories that were longer than 150 characters.

      Based on community input, the GitHub Copilot team also developed a code reference tool that includes links to public code that may match GitHub Copilot suggestions, so developers can review potential matches (and relevant licensing information), and make informed choices.

    Develop a go-to-market strategy

    • Launch your product with product evangelists. Before launching the technical preview of GitHub Copilot in 2021, the team presented the prototype to influential members of the software developer community and GitHub Stars. This allowed us to launch the technical preview with an existing base of support and extend the preview’s reach to a broader range of users.

    • Get your product in front of individual users before going after businesses. The team decided to first sell licenses directly to developers, who would clearly benefit from an AI coding assistant. We paired this approach with a free trial program and monthly pricing, based on user survey findings that individuals prefer a simple and predictable subscription. Gaining traction among individual users helped to build a foundation of support and drive adoption at the enterprise level.

    Key takeaways

    We’re still in the early days of generative AI, so we’re keeping close tabs on the demand and need for this new technology. While each company and product will need to define its own approach to building an LLM app, here are some key learnings from our product journey with GitHub Copilot:

    • Identify a focused problem and thoughtfully discern an AI’s use cases. This will ensure your app has greater impact and a faster time-to-market.

    • Integrate experimentation and tight feedback loops into the design process. This is especially critical when working with LLMs, where outputs are probabilistic and most end users are just learning how to interact with AI models.

    • As you scale, continue to leverage user feedback and prioritize user needs. Doing so will ensure that your product is built to deliver consistent results and real value.

    If you’re looking for a problem to solve with an LLM app, check out our post on how companies are boosting productivity with generative AI. You can also take lessons from how GitHub used GitHub Actions to help an AI nonprofit, Ersilia, disseminate AI models to advance pharmaceutical research in low- and middle-income countries.

    The post How to build an enterprise LLM application: Lessons from GitHub Copilot appeared first on The GitHub Blog.

    A developer’s guide to prompt engineering and LLMs

    Post Syndicated from Albert Ziegler original https://github.blog/2023-07-17-prompt-engineering-guide-generative-ai-llms/


    In a blog post authored back in 2011, Marc Andreessen warned that, “Software is eating the world.” Over a decade later, we are witnessing the emergence of a new type of technology that’s consuming the world with even greater voracity: generative artificial intelligence (AI). This innovative AI includes a unique class of large language models (LLM), derived from a decade of groundbreaking research, that are capable of out-performing humans at certain tasks. And you don’t have to have a PhD in machine learning to build with LLMs—developers are already building software with LLMs with basic HTTP requests and natural language prompts.

    In this article, we’ll tell the story of GitHub’s work with LLMs to help other developers learn how to best make use of this technology. This post consists of two main sections: the first will describe at a high level how LLMs function and how to build LLM-based applications. The second will dig into an important example of an LLM-based application: GitHub Copilot code completions.

    Others have done an impressive job of cataloging our work from the outside. Now, we’re excited to share some of the thought processes that have led to the ongoing success of GitHub Copilot.

    Let’s jump in.

    Everything you need to know about prompt engineering in 1600 tokens or less

    You know when you’re tapping out a text message on your phone, and in the middle of the screen just above the keypad, there’s a button you can click to accept a suggested next word? That’s pretty much what an LLM is doing—but at scale.

    A GIF show autocomplete functionalities in iOS.
    An example of iMessage’s text prediction feature.

    Instead of text on your phone, an LLM works to predict the next best group of letters, which are called “tokens.” And in the same way that you can keep tapping that middle button to complete your text message, the LLM completes a document by predicting the next word. It will continue to do that over and over, and it will only stop once it has reached a maximum threshold of tokens or once it has encountered a special token that signals “Stop! This is the end of the document.”

    There’s an important difference, though. The language model in your phone is pretty simple—it’s basically saying, “Based only upon the last two words entered, what is the most likely next word?” In contrast, an LLM produces an output that’s more akin to being “based upon the full content of every document ever known to exist in the public domain, what is the most likely next token in your document?” By training such a large, well-architected model on an enormous dataset, an LLM can almost appear to have common sense such as understanding that a glass ball sitting on a table might roll off and shatter.

    A screenshot of ChatGPT answering a question about the danger of setting a round glass ball on a small table.
    Example of an LLM’s awareness or “common sense” due to its training.

    But be warned: LLMs will also sometimes confidently produce information that isn’t real or true, which are typically called “hallucinations” or “fabulations.” LLMs can also appear to learn how to do things they weren’t initially trained to do. Historically, natural language models have been created for one-off tasks, like classifying the sentiment of a tweet, extracting the business entities from an email, or identifying similar documents, but now you can ask AI tools like ChatGPT to perform a task that it was never trained to do.

    A screenshot of ChatGPT answering a prompt to create a chicken-based limerick.
    John conversing with ChatGPT about serious things.

    Building applications using LLMs

    A document completion engine is a far cry from the amazing proliferation of LLM applications that are springing up every day, running the gamut from conversational search, writing assistants, automated IT support, and code completion tools, like GitHub Copilot. But how is it possible that all of these tools can come from what is effectively a document completion tool? The secret is any application that uses an LLM is actually mapping between two domains: the user domain and the document domain.

    A graphic showing how LLMs work and the processes behind them to determine context before giving an answer.
    Diagram of the user flow when communicating with an LLM, in this case, Dave’s user flow.

    On the left is the user. His name is Dave, and he has a problem. It’s the day of his big World Cup watch party, and the Wi-Fi is out. If they don’t get it fixed soon, he’ll be the butt of his friends’ jokes for years. Dave calls his internet provider and gets an automated assistant. Ugh! But imagine that we are implementing the automated assistant as an LLM application. Can we help him?

    The key here is to figure out how to convert from user domain into document domain. For one thing, we will need to transcribe the user’s speech into text. As soon as the automated support agent says “Please state the nature of your cable-related emergency,” Dave blurts out:

    Oh it’s awful! It’s the World Cup finals. My TV was connected to my Wi-Fi, but I bumped the counter and the Wi-Fi box fell off and broke! Now, we can’t watch the game.

    At this point, we have text, but it’s not of much use. Maybe you would imagine that this was part of a story and continue it, “I guess, I’ll call up my brother and see if we can watch the game with him.” An LLM with no context will similarly create the continuation of Dave’s story. So, let’s give the LLM some context and establish what type of document this is:

    ### ISP IT Support Transcript:
    
    The following is a recorded conversation between an ISP customer, Dave Anderson, and Julia Jones, IT support expert. This transcript serves as an example of the excellent support provided by Comcrash to its customers.
    
    *Dave: Oh it's awful! This is the big game day. My TV was connected to my Wi-Fi, but I bumped the counter and the Wi-Fi box fell off and broke! Now we can't watch the game.
    *Julia:
    

    Now, if you found this pseudo document on the ground, how would you complete it? Based on the extra context, you would see that Julia is an IT support expert, and apparently a really good one. You would expect the next words to be sage advice to help Dave with his problem. It doesn’t matter that Julia doesn’t exist, and this wasn’t a recorded conversation—what matters is that these extra words offer more context for what a completion might look like. An LLM does the same exact thing. After reading this partial document, it will do its best to complete Julia’s dialogue in a helpful manner.

    But there’s more we can do to make the best document for the LLM. The LLM doesn’t know a whole lot about cable TV troubleshooting. (Well, it has read every manual and IT document ever published online, but stay with me here). Let’s assume that its knowledge is lacking in this particular domain. One thing we can do is search for extra content that might help Dave and place it into the document. Let’s assume that we have a complaints search engine that allows us to find documentation that has been helpful in similar situations in the past. Now, all we have to do is weave this information into our pseudo document in a natural place.

    Continuing from above:

    *Julia:(rifles around in her briefcase and pulls out the perfect documentation for Dave's request)
    Common internet connectivity problems ...
    <...here we insert 1 page of text that comes from search results against our customer support history database...>
    (After reading the document, Julia makes the following recommendation)
    *Julia:
    

    Now, given this full body of text, the LLM is conditioned to make use of the implanted documentation, and in the context of “a helpful IT expert,” the model will generate a response. This reply takes into account the documentation as well as Dave’s specific request.

    The last step is to move from the document domain into the user’s problem domain. For this example, that means just converting text to voice. And since this is effectively a chat application, we would go back and forth several times between the user and the document domain, making the transcript longer each time.

    This, at the core of the example, is prompt engineering. In the example, we crafted a prompt with enough context for the AI to produce the best possible output, which in this case was providing Dave with helpful information to get his Wi-Fi up and running again. In the next section, we’ll take a look at how we at GitHub have refined our prompt engineering techniques for GitHub Copilot.

    The art and science of prompt engineering

    Converting between the user domain and document domain is the realm of prompt engineering—and since we’ve been working on GitHub Copilot for over two years, we’ve started to identify some patterns in the process.

    These patterns have helped us formalize a pipeline, and we think it is an applicable template to help others better approach prompt engineering for their own applications. Now, we’ll demonstrate how this pipeline works by examining it in the context of GitHub Copilot, our AI pair programmer.

    The prompt engineering pipeline for GitHub Copilot

    From the very beginning, GitHub Copilot’s LLMs have been built on AI models from OpenAI that have continued to get better and better. But what hasn’t changed is the answer to the central question of prompt engineering: what kind of document is the model trying to complete?

    The OpenAI models we use have been trained to complete code files on GitHub. Ignoring some filtering and stratification steps that don’t really change the prompt engineering game, this distribution is pretty much that of individual file contents according to the most recent commit to main at data collection time.

    The document completion problem the LLM solves is about code, and GitHub Copilot’s task is all about completing code. But the two are very different.

    Here are some examples:

    • Most files committed to main are finished. For one, they usually compile. Most of the time the user is typing, the code does not compile because of incompletions that will be fixed before a commit is pushed.
    • The user might even write their code in hierarchical order, method signatures first, then bodies rather than line by line or in a mixed style.
    • Writing code means jumping around. In particular, people’s edits often require them to jump up in the document and make a change there, for example, adding a parameter to a function. Strictly speaking, if Codex suggests using a function that has not been imported yet, no matter how much sense it might make, that’s a mistake. But as a GitHub Copilot suggestion, it would be useful.

    The issue is that merely predicting the most likely continuation based on the text in front of the cursor to make a GitHub Copilot suggestion would be a wasted opportunity. That’s because it ignores an incredible wealth of context. We can use that context to guide the suggestion, like metadata, the code below the cursor, the content of imports, the rest of the repository, or issues, and create a strong prompt for the AI assistant.

    Software development is a deeply interconnected, multimodal challenge, and the more of that complexity we can tame and present to the model, the better your completions are going to be.

    Step 1: Gathering context

    GitHub Copilot lives in the context of an IDE such as Visual Studio Code (VS Code), and it can use whatever it can get the IDE to tell it—only if the IDE is quick about it though. In an interactive environment like GitHub Copilot, every millisecond matters. GitHub Copilot promises to take care of the common coding tasks, and if it wants to do that, it needs to display its solution to the developer before they have started to write more code in their IDE. Our rough heuristics say that for every additional 10 milliseconds we take to come up with a suggestion, the chance it’ll arrive in time decreases by one percent.

    So, what can we say quickly? Well, here’s an example. Consider this suggestion to a simple piece of Python:

    A developer prompting GitHub Copilot to write a simple function in Python to compute Fibonacci numbers.

    Wrong! Turns out the user actually wanted to write Ruby, like this:

    A developer using GitHub Copilot to write a simple function to compute Fibonacci numbers in Ruby.

    The two languages have similar enough syntax so that only a couple of lines can be ambiguous, especially when it’s toward the beginning of the file where much of what we encounter are boilerplate comments. But modern IDEs such as VS Code typically know what language the user is writing in. That makes language mix ups especially annoying to the user because they break the implicit expectation that “the computer should know” (after all, most IDEs highlight language syntax).

    So, let’s put the language metadata into our pile of context we might want to include. In fact, let’s add the whole filename too. If it’s available, it usually implies the language through its extension, and additionally sets the tone for what to expect in that file—small, easy pieces of information that won’t turn the tide but are helpful to include.

    On the other end of the spectrum, there’s the rest of the repository. Say you’ve got a file that defines an abstract class DataReader. And you have another that defines a subclass CsvReader. And you’re now writing a new file defining another subclass SqlReader. Chances are that to write the new file, you’ll want to check out both existing files as well because they communicate useful background into what you need to implement and how to do it. Typically, developers keep such files open in different tabs and switch to remind themselves of definitions, examples, similar patterns, or tests.

    If the content of those two files is useful to you, chances are it would be useful to the AI as well. So, let’s add it as context! After all, the IDE knows what other files from the repository are open as tabs in the same window. The repository might have hundreds or even thousands of files, but only some will be open, and that is a strong hint that they might be useful to what they’re doing right now. Of course, “some” can mean a lot of things, so we don’t consider any more than the 20 most recent tabs.

    Step 2: Snippeting

    Irrelevant information in an LLM’s context decreases its accuracy. Additionally, source code tends to be long, so even a single file is not guaranteed to fit completely into an LLM’s context window (a problem that occurs roughly a fifth of the time). So, unless the user is very frugal about their tab usage, we simply cannot include all the tabs.

    It’s important to be selective about what code to include from other files, so we cut files into (hopefully) natural, overlapping snippets that are no longer than 60 lines. Of course, we don’t want to actually include all overlapping snippets—that’s why we score them and take only the best. In this case, the “score” is meant to reflect relevance. To determine a snippet’s score, we use the Jaccard similarity, a stat that can be used to gauge the similarity or diversity of sample sets. (It’s also super fast to compute, which is great for reducing latency.)

    Step 3: Dressing them up

    Now we have some context we’d like to pass on to the model. But how? Codex and other models don’t offer an API where you can add other files, or where you can specify the document’s language and filename for that matter. They complete one single document. As mentioned above, you’ll need to inject your context into that document in a natural way.

    The path and name might be easiest. Many files start with a preamble that gives some metadata, like author, project name, or filename. So, we’ll pretend this is happening here as well, and add a line at the very top that reads something like # filepath: foo/bar.py or // filepath: foo.bar.js, depending on comment syntax in the file’s language.

    Sometimes the path isn’t known, like with new files that haven’t yet been saved. Even then, we could try to at least specify the language, provided the IDE is aware of it. For many languages, we have the opportunity to include shebang lines like #!/usr/bin/python or #!/usr/bin/node. That’s a neat trick that works pretty well at warding against mistaken language identity. But it’s also a bit dangerous since files with shebang lines are a biased subpopulation of all code. So, let’s do it for short files where the danger of mistaken language identity is high, and avoid it for larger or named files.

    If comments work as a delivery system for tiny nuggets of information, like path or language, we can also make them work as delivery systems for the chunky deep dives that are 60 lines of related code.

    Comments are versatile, and commented-out code exists all over GitHub. Let’s look at some of the most common examples:

    • Old code that doesn’t apply anymore
    • Deleted features
    • Earlier versions of current code
    • Example code specifically left there for documentation purposes
    • Code lifted from other parts of the codebase

    Let’s take our inspiration from the last group of examples. Familiarity with groups (1) – (3) makes things a bit easier on the model, but our snippets aim to emulate groups (4) and (5):

    # compare this snippet from utils/concatenate.py:
    
    # def crazy_concat(a, b):
    
    # return str(a) + str(b)[::-1]
    

    Note that including the file name and path of the snippet source can be useful. And combined with the current file’s path, this might guide completions referencing imports.

    Step 4: Prioritization

    So far, we have grabbed many pieces of context from many sources: the text directly above the cursor, text below the cursor, text in other files, and metadata like language and file path.

    In the vast majority of cases (around 95%), we have to make the tough choice of what we can or cannot include.

    We make that choice by thinking of the items we might include as “wishes.” Each time we uncover a piece of context, like a commented out snippet from an open tab, we make a wish. Wishes come with some priority attached, for example, the shebang lines have rather low priorities. Snippets with a low similarity score are barely higher. In contrast, the lines directly above the cursor have maximum priority. Wishes also come with a desired position in the document. The shebang line needs to be the very first item, while the text directly above the cursor comes last—it should directly precede the LLM’s completion.

    The fastest way of selecting which wishes to fill and which ones to discard is by sorting that wishlist by priority. Then, we can keep deleting the lowest priority wishes until what remains fits in the context window. We then sort again by the intended order in the document and paste everything together.

    Step 5: The AI does its thing

    Now that we’ve assembled an informative prompt, it’s time for the AI to come up with a useful completion. We have always faced a very delicate tradeoff here—GitHub Copilot needs to use a highly capable model because quality makes all the difference between a useful suggestion and a distraction. But at the same time, it needs to be a model capable of speed, because latency makes all the difference between a useful suggestion and not being able to provide a suggestion at all.

    So, which AI should we choose to “do its thing” on the completion task: the fastest or the most accurate one? It’s hard to know in advance, so OpenAI developed a fleet of models in collaboration with GitHub. We put two different models in front of developers but found that people got the most mileage (in terms of accepted and retained completions) out of the much faster model. Since then, further optimizations have increased model speed significantly, so that the current version of GitHub Copilot is backed by an even more capable model.

    Step 6: Now, over to you!

    The generative AI produces a string, and if it’s not stopped, it keeps on producing and will keep going until it predicts the end of the file. That would waste time and compute resources, so you need to set up “stop” criteria.

    The most common stop criterion is actually looking for the first line break. In many situations, it seems likely that a software developer wants the current line to be finished, but not more. But some of the most magical contributions by GitHub Copilot are when it suggests multiple lines of code all at once.

    Multi-line completions feel natural when they’re about a single semantic unit, such as the body of a function, an if-branch, or a class. GitHub Copilot looks for cases where such a block is being started, either because the developer has just written the start, such as the header, if guard, or class declaration, or is currently writing the start. If the block body appears to be empty, it will attempt to make a suggestion for it, and only stop when the block appears to be done.

    This is the point when the suggestion gets surfaced to the coder. And the rest, as they say, is ~~history~~ 10x development.

    If you’re interested in learning more about prompt engineering in general and how you can refine your own techniques, check out our guide on getting started with GitHub Copilot.

    How GitHub Copilot is getting better at understanding your code

    Post Syndicated from Johan Rosenkilde original https://github.blog/2023-05-17-how-github-copilot-is-getting-better-at-understanding-your-code/

    To make working with GitHub Copilot feel like a meeting of the minds between developers and the pair programmer, GitHub’s machine learning experts have been busy researching, developing, and testing new capabilities—and many are focused on improving the AI pair programmer’s contextual understanding. That’s because good communication is key to pair programming, and inferring context is critical to making good communication happen.

    To pull back the curtain, we asked GitHub’s researchers and engineers about the work they’re doing to help GitHub Copilot improve its contextual understanding. Here’s what we discovered.

    From OpenAI’s Codex model to GitHub Copilot

    When OpenAI released GPT-3 in June 2020, GitHub knew developers would benefit from a product that leveraged the model specifically for coding. So, we gave input to OpenAI as it built Codex, a descendant of GPT-3 and the LLM that would power GitHub Copilot. The pair programmer launched as a technical preview in June 2021 and became generally available in June 2022 as the world’s first at-scale generative AI coding tool.

    To ensure that the model has the best information to make the best predictions with speed, GitHub’s machine learning (ML) researchers have done a lot of work called prompt engineering (which we’ll explain in more detail below) so that the model provides contextually relevant responses with low latency.

    Though GitHub’s always experimenting with new models as they come out, Codex was the first really powerful generative AI model that was available, said David Slater, a ML engineer at GitHub. “The hands-on experience we gained from iterating on model and prompt improvements was invaluable.”

    All that experimentation resulted in a pair programmer that, ultimately, frees up a developer’s time to focus on more fulfilling work. The tool is often a huge help even for starting new projects or files from scratch because it scaffolds a starting point that developers can adapt and tweak as desired, said Alice Li, a ML researcher at GitHub.

    I still find myself impressed and even surprised by what GitHub Copilot can do, even after having worked on it for some time now.

    – Alice Li, ML researcher at GitHub

    Why context matters

    Developers use details from pull requests, a folder in a project, open issues, and more to contextualize their code. When it comes to a generative AI coding tool, we need to teach that tool what information to use to do the same.

    Transformer LLMs are good at connecting the dots and big-picture thinking. Generative AI coding tools are made possible by large language models (LLMs). These models are sets of algorithms trained on large amounts of code and human language. Today’s state-of-the-art LLMs are transformers, which makes them adept at making connections between text in a user’s input and the output that the model has already generated. This is why today’s generative AI tools are providing responses that are more contextually relevant than previous AI models.

    But they need to be told what information is relevant to your code. Right now, transformers that are fast enough to power GitHub Copilot can process about 6,000 characters at a time. While that’s been enough to advance and accelerate tasks like code completion and code change summarization, the limited amount of characters means that not all of a developer’s code can be used as context.

    So, our challenge is to figure out not only what data to feed the model, but also how to best order and enter it to get the best suggestions for the developer.

    Learn more about LLMs, generative AI coding tools, and how they’re changing the way developers work.

    How GitHub Copilot understands your code

    It all comes down to prompts, which are compilations of IDE code and relevant context that’s fed to the model. Prompts are generated by algorithms in the background, at any point in your coding. That’s why GitHub Copilot will generate coding suggestions whether you’re currently writing or just finished a comment, or in the middle of some gnarly code.

    • Here’s how a prompt is created: a series of algorithms first select relevant code snippets or comments from your current file and other sources (which we’ll dive into below). These snippets and comments are then prioritized, filtered, and assembled into the final prompt.

    GitHub Copilot’s contextual understanding has continuously matured over time. The first version was only able to consider the file you were working on in your IDE to be contextually relevant. But we knew context went beyond that. Now, just a year later, we’re experimenting with algorithms that will consider your entire codebase to generate customized suggestions.

    Let’s look at how we got here:

    • Prompt engineering is the delicate art of creating a prompt so that the model makes the most useful prediction for the user. The prompt tells LLMs, including GitHub Copilot, what data, and in what order, to process in order to contextualize your code. Most of this work takes place in what’s called a prompt library, which is where our in-house ML experts work with algorithms to extract and prioritize a variety of sources of information about the developer’s context, creating the prompt that’ll be processed by the GitHub Copilot model.

    • Neighboring tabs is what we call the technique that allows GitHub Copilot to process all of the files open in a developer’s IDE instead of just the single one the developer is working on. By opening all files relevant to their project, developers automatically invoke GitHub Copilot to comb through all of the data and find matching pieces of code between their open files and the code around their cursor—and add those matches to the prompt.

    When developing neighboring tabs, the GitHub Next team and in-house ML researchers did A/B tests to figure out the best parameters for identifying matches between code in your IDE and code in your open tabs. They found that setting a very low bar for when to include a match actually made for the best coding suggestions.

    By including every little bit of context, neighboring tabs helped to relatively increase user acceptance of GitHub Copilot’s suggestions by 5%**.

    Even if there was no perfect match—or even a very good one—picking the best match we found and including that as context for the model was better than including nothing at all.

    – Albert Ziegler, principal ML engineer at GitHub
    • The Fill-In-the-Middle (FIM) paradigm widened the context aperture even more. Prior to FIM, only the code before your cursor would be put into the prompt—ignoring the code after your cursor. (At GitHub, we refer to code before the cursor as the prefix and after the cursor as the suffix.) With FIM, we can tell the model which part of the prompt is the prefix, and which part is the suffix.

    Even if you’re creating something from scratch and have a skeleton of a file, we know that coding isn’t linear or sequential. So, while you bounce around your file, FIM helps GitHub Copilot offer better coding suggestions for the part in your file where your cursor is located, or the code that’s supposed to come between the prefix and suffix.

    Based on A/B testing, FIM gave a 10% relative boost in performance, meaning developers accepted 10% more of the completions that were shown to them. And thanks to optimal use of caching, neighboring tabs and FIM work in the background without any added latency.

    System diagram focused on model quality efforts. The diagram starts on the left with inputs from open tabs, data from editor, and vector database, which feed into a prompt library. (We are continuously working on improvements to provide better context from available sources in the prompt.) This then goes into the prompt, which is fed through a contextual filter model and a GPT model. (We are continuously working on new and improved model engines optimized for GitHub Copilot.) This model provides completions to fill in the middle of the prompt prefix and suffix. From the models, n completions are generated, and less than or equal to n completions are shown.

    Improving semantic understanding

    Today, we’re experimenting with vector databases that could create a customized coding experience for developers working in private repositories or with proprietary code. Generative AI coding tools use something called embeddings to retrieve information from a vector database.

    • What’s a vector database? It’s a database that indexes high-dimensional vectors.

    • What’s a high-dimensional vector? They’re mathematical representations of objects, and because these vectors can model objects in a number of dimensions, they can capture complexities of that object. When used properly to represent pieces of code, they may represent both the semantics and even intention of the code—not just the syntax.

    • What’s an embedding? In the context of coding and LLMs, an embedding is the representation of a piece of code as a high-dimensional vector. Because of the “knowledge” the LLM has of both programming and natural language, it’s able to capture both the syntax and semantics of the code in the vector.

    Here’s how they’d all work together:

    • Algorithms would create embeddings for all snippets in the repository (potentially billions of them), and keep them stored in the vector database.
    • Then, as you’re coding, algorithms would embed the snippets in your IDE.
    • Algorithms would then make approximate matches—also, in real time—between the embeddings that are created for your IDE snippets and the embeddings already stored in the vector database. The vector database is what allows algorithms to quickly search for approximate matches (not just exact ones) on the vectors it stores, even if it’s storing billions of embedded code snippets.

    Developers are familiar with retrieving data with hashcodes, which typically look for exact character by character matches, explained Alireza Goudarzi, senior ML researcher at GitHub. “But embeddings—because they arise from LLMs that were trained on a vast amount of data—develop a sense of semantic closeness between code snippets and natural language prompts.”

    Read the three sentences below and identify which two are the most semantically similar.

    • Sentence A: The king moved and captured the pawn.
    • Sentence B: The king was crowned in Westminster Abbey.
    • Sentence C: Both white rooks were still in the game.

    The answer is sentences A and C because both are about chess. While sentences A and B are syntactically, or structurally similar because both have a king as the subject, they’re semantically different because “king” is used in different contexts.

    Here’s how each of those statements could translate to Python. Note the syntactic similarity between snippets A and B despite their semantic difference, and the semantic similarity between snippets A and C despite their syntactic difference.

    Snippet A:

    if king.location() == pawn.location():
        board.captures_piece(king, pawn)
    

    Snippet B:

    if king.location() == "Westminster Abbey":
        king.crown()
    

    Snippet C:

    if len([ r for r in board.pieces("white") if r.type == "rook" ]) == 2:
        return True
    

    As mentioned above, we’re still experimenting with retrieval algorithms. We’re designing the feature with enterprise customers in mind, specifically those who are looking for a customized coding experience with private repositories and would explicitly opt in to use the feature.

    Take this with you

    Last year, we conducted quantitative research on GitHub Copilot and found that developers code up to 55% faster while using the pair programmer. This means developers feel more productive, complete repetitive tasks more quickly, and can focus more on satisfying work. But our work won’t stop there.

    The GitHub product and R&D teams, including GitHub Next, have been collaborating with Microsoft Azure AI-Platform to continue bringing improvements to GitHub Copilot’s contextual understanding. So much of the work that helps GitHub Copilot contextualize your code happens behind the scenes. While you write and edit your code, GitHub Copilot is responding to your writing and edits in real time by generating prompts–or, in other words, prioritizing and sending relevant information to the model based on your actions in your IDE—to keep giving you the best coding suggestions.


    Learn more