Tag Archives: LLM

The Lifecycle of LLM-as-a-Judge: Building, Aligning, and Monitoring at scale

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/the-lifecycle-of-llm-as-a-judge-building-aligning-and-monitoring-at-scale-c95bd8283508

By Emma Yanyang Kong, JJ Tan, Ishan Gupta, Lars Olds, Claire Campbell, David Fagnan, Ratna Kavuri, Rohan Gosain, Veli Balin, Minsu Jang, Louis Garcia

Introduction

Any team generating text with an LLM at scale hits the same problem. You cannot evaluate everything manually. You don't know which outputs are great, which are mediocre, and which are harmful, because you simply cannot read them all. The standard solution is LLM-as-a-Judge, a second model that scores the first model’s output as a proxy for human raters. It is fast, cheap, and easy to deploy. However, it introduces a new and critical question: Who evaluates the evaluator? Furthermore, if the judge drifts, quietly degrading and starting to approve bad output, nothing downstream will flag it.

This post is about how we solve that problem, by building, aligning, and continuously monitoring LLM judges so they stay trustworthy over time. Our core principle is simple: An LLM judge must never operate alone. It has to be anchored in human judgment. We keep a human-in-the-loop (HITL) at every phase of the lifecycle. Humans define what “good” means, create the labeled benchmark datasets to train and validate the judge, monitor its behavior while it runs in the system, and review and approve any updates before they’re rolled out.

We believe:

A reliable LLM judge is not a static artifact. It has a lifecycle.

It needs to be built against trusted human labels, aligned with human preference and reasoning, run under human-set policy, and maintained as the data and usage pattern shift. Each of these stages has human owners. In the sections below, we walk through these four phases, the key design decisions in each, and the lessons we’d share with a team building their own LLM judge, using one concrete task as our running example: recommendation explanations.

A recommendation explanation is a short natural-language message that accompanies a recommended item, and it shapes how users perceive and trust a recommender system. In our work, an explanation is human-readable evidence for why a title was recommended based on what the member has previously watched, shown on the title’s detail page, which is the screen a member reaches by selecting a title from the homepage. We focus on similarity-based explanations, which connect a recommended title to one reference title the member has interacted with via shared attributes such as genre and tone. For example,

A funny, heartfelt holiday romance about love and new beginnings, much like “My Secret Santa.”

Quality matters here because a misleading or poorly grounded explanation erodes the very trust the explanation is meant to build.

Everything that follows comes out of a series of controlled, user-facing online experiments we ran on the explanation feature, including a month-long experiment on the Netflix mobile app. In these tests we used an LLM to generate explanations, hundreds of thousands a week across a constantly changing catalog. Manually reviewing them at this scale isn’t feasible, so we deployed a second LLM to evaluate them.

What counts as a good explanation is specific to our task. However, the way we build, align, and monitor the LLM judge for evaluating explanations should be reusable and generalizable across different tasks.

The Lifecycle at a Glance

Figure 1 summarizes the four phases of our LLM-judge lifecycle and the data flow connecting them.

Figure 1. The four-phase lifecycle of an LLM judge, and the data that flows between the phases.

We start with Birth: Benchmark Data Creation, where human experts craft hard or near-boundary examples and human raters label them with pass/fail decisions and written rationales. We augment this with LLM-generated gray-area examples to build a richer benchmark dataset.

Next, in the second phase of Training: LLM Judge Development, we tune the LLM judge to align with human labels and rationales from the Birth phase, using self-reflection to identify mismatches between the judge and humans, and updating the rubrics based on those mismatches and anchor examples. We iterate in this phase until our metrics show that the judge is sufficiently aligned with human raters.

In the third phase, Deployment, we integrate the judge into the explanation generation system as both a gate and a critic. The LLM generator writes explanations, and the LLM judge scores them and either passes them through or blocks them and supplies a rationale that the generator can use for self-refinement and retries. Passed explanations are served to members, and low-quality explanations are gated.

Finally, in the last phase, HITL Alignment & Drift Monitoring, we keep the judge aligned with humans over time. “Human-in-the-loop” here means a person is directly involved in the decision, not just reviewing outcomes after the fact. We benchmark the judge against trained raters, and a human approves every change before it is rolled out to the system. During each test we sampled a set of explanations each week (both passed and gated, with a bias toward newer items), had human raters review them with labels and rationales, and compared the judge against these human ratings. If drift exceeded a threshold, we triggered retraining and benchmark data augmentation. This closes the loop by feeding new human-labeled data and updated signals back into the benchmark and development phases.

System components

Four automated components appear across all phases, alongside the human roles that define, validate, and supervise them.

  • Generator: produces the explanation text, optionally using prior judge rationales and traces as part of its prompt for revision.
  • Judge: evaluates an explanation and returns a pass/fail label together with a written rationale. In the deployed pipeline, it acts as both a guardrail (gating bad outputs) and a critic (providing feedback for self-refinement).
  • Reflector: revises the Judge’s rubric when the Judge makes mistakes. It updates the rubric based on mismatched examples, human rationales, and anchor examples. It tunes the rubric and does not directly evaluate explanations.
  • Meta-Judge: checks whether the Judge failed an explanation for the right reason by comparing the Judge’s rationale against a human rater’s rationale.
  • Human experts and raters: the experts who define the quality criteria; the raters whose labels and written rationales the Judge is tuned and measured against; the reviewers who monitor the Judge while it is running and explicitly approve any changes before they were rolled out.

Phase I, Birth: Establishing Ground Truth

Everything downstream depends on knowing what “good” means, so this is the most human-intensive phase. Our internal writing experts define the must-have criteria an explanation must satisfy, author detailed labeling guidelines, and hand-craft tricky adversarial examples. Those same guidelines do double duty. They’re both the rulebook for human raters and the seed rubric for the LLM judges we tune later.

Why we built our own benchmark

Off-the-shelf LLM-judge benchmarks focus on general-purpose text evaluation and miss what makes our task specific. Explanations are short, item-specific, and context-dependent (each one is tied to a target title and one or two reference titles the member has watched). We also care about alignment to our own editorial bar, not just generic language quality. As a result, we built our own custom benchmark from three complementary sources:

  • Expert-crafted adversarial cases: hand-authored pass/fail examples with known failure modes, the kind of edge cases nothing else reliably produces.
  • Boundary examples: LLM-synthesized explanations that are deliberately pushed near the pass/fail boundary, then rated by humans. These capture the ambiguous cases that sampling from live traffic rarely surfaces on its own.
  • Real sampled explanations: explanations sampled from the output of our LLM generator during test runs.

Two details that mattered

  • The benchmark is not frozen. A monitoring pipeline (Phase IV) appends a fresh batch of human-rated explanations on a weekly cadence, so over the course of a test the benchmark tracked the current catalog and new usage patterns instead of going stale.
  • Every “fail” label carries a free-text rationale explaining why the explanation failed. This looks like a small bookkeeping detail, but it is actually critical for the next phase, since those rationales are what we use to tune and audit the judge’s reasoning.

Phase II, Training: Aligning the Judge to Humans

The failure mode: right answer, wrong reason

There is a failure mode that does not show up in label-agreement metrics at all. A judge can agree with humans on the label, passing when they would pass and failing when they would fail, while reaching the right verdict for the wrong reason. On a dashboard it looks perfectly aligned. But as soon as you ask it to explain a rejection, which our pipeline does to steer self-revision, it can return misleading guidance.

We therefore care about not just label agreement but also reasoning alignment. In our setup, the Judge is always asked to output:

  • a label (e.g., PASS/FAIL), and
  • a short natural-language rationale for that label.

Here is an illustrative example. The member watched a musical, a family fantasy with a young heroine and a well-known ensemble cast. We recommend an adventure movie that is also a family fantasy with a young heroine, which is why the recommender paired them. But it shares neither the songs nor the ensemble cast.

The label (FAIL) is correct, and the stated reason is reasonable at first glance. But it turns out to be incomplete in a way that simple label agreement cannot detect, as we show below.

Reasoning-Aligned Rubric Tuning

We tune each criterion’s LLM Judge with a procedure we call Reasoning-Aligned Rubric Tuning (RART). As introduced in the system components above, the Judge, Meta-Judge, and Reflector are distinct components. The Judge scores an explanation against a rubric and gives a rationale, the Meta-Judge compares that rationale against a human-written one, and the Reflector edits the rubric text itself. RART is how the three are combined into a training loop.

Every Judge is a fixed prompt template parameterized by a rubric, so tuning it does not mean retraining the underlying model. Instead we iteratively refine the rubric text until the Judge’s behavior matches human labels and human rationales. At iteration i, the Judge is conditioned on the current rubric text and maps an explanation to a pair, a label and a rationale.

R_i is the current rubric text, y_J(x) the label, and r_J(x) the rationale.

At a high level, each RART iteration proceeds as follows.

  1. Score the training data with the current rubric.
  2. Evaluate weighted alignment metrics on a held-out validation set. If all per-criterion metrics exceed their thresholds, stop.
  3. Otherwise, construct an error-driven focus set of misaligned examples and hand it to the Reflector, which proposes a revised rubric.

The key difference from a standard loop is how we define a “mistake.” Most self-improvement loops look only at label disagreements. RART adds a second class of error. The Meta-Judge examines the cases where the Judge and a human both said fail and compares the Judge’s stated reason against the human’s rationale. When the two diverge, that is a right answer, wrong reason error, and it is also fed to the Reflector. Concretely, the focus set handed to the Reflector is the union of two error classes:

  • Label mismatches: examples where the Judge’s label differs from the human’s.
  • Right label, wrong reason: examples where the Judge and the human both said FAIL, but the Meta-Judge finds their two rationales don’t match.

So the Reflector revises the rubric from both ordinary label errors and right label, wrong reason errors. That second term is the core of RART. The Judge is pushed not only to match human decisions but to justify them in a way the Meta-Judge recognizes as aligned with human reasoning.

Returning to the earlier example, the LLM Judge said FAIL and a human said FAIL, so a label-only check would register agreement. Placing the two reasons side by side shows what that check misses.

RART routes it into the focus set, so the next rubric revision has to account for it.

Since the Meta-Judge is an LLM too, we checked it against humans first. Trained human raters labeled a sample of agreed-fail rationale pairs, and the Meta-Judge matched their verdicts on nearly all of them.

Alignment metrics

We run one Judge per criterion, each with its own rubric, tuned and scored on its own. So everything below is measured per criterion on held-out data. For each one we track three metrics.

  • Specificity (fail-recall): how often the Judge correctly rejects bad explanations. This is the one we care about most, because a bad explanation that slips through the gate is a trust hazard.
  • Recall (pass-recall): how often it correctly passes good explanations, which keeps coverage high and revision cost low.
  • Reasoning agreement: on the explanations both reject, how often they reject for the same reason.

Each criterion’s Judge gets its own three, and one can be healthy while another slips. That is also why the gate is strict. An explanation has to pass every must-have criterion to be eligible to serve.

Ablation: does the reasoning signal help?

To isolate the impact of the reasoning signal, we compare RART to an otherwise identical loop that uses only label disagreements. We call this baseline vanilla: same Reflector, same Judge, same data, but no Meta-Judge and no use of human rationales.

Figure 2. Improvement over the starting rubric, per criterion, for reasoning-aware tuning (RART) and label-only tuning (vanilla).

Figure 2 shows the result. On two of the three must-have criteria, vanilla and RART land in the same place, because the starting rubric was already near ceiling and the metrics had very little room to gain. On the third criterion, the vanilla (label-only) method degrades. The Reflector in the vanilla loop rewrites the rubric into degenerate forms, and specificity and reasoning agreement fall with every iteration, ending up worse than the rubric it started from. RART stays stable on that same criterion and lifts both, with a small recall gain as well. The reason is that a vanilla (label-only) optimizer can reach the right label through unsound reasoning, and unsound reasoning doesn’t generalize to new data. Anchoring the signal on the rationale prevents that. Reasoning alignment helps where there is headroom and doesn’t hurt where there isn’t.

Phase III, Deployment: Putting the Judge to Work

Once deployed, the judge sat inside the generation pipeline, gating and critiquing explanations as they were produced during our tests.

Two roles for one judge

Once we align the LLM Judge with humans, we reuse it in two distinct roles for every generated explanation:

  • Role 1, the gate. The Judge scores each explanation against the must-have criteria and rejects anything that fails.
  • Role 2, the critic. When an explanation fails, we don’t just throw it away. The Judge’s free-text reason gets appended to the Generator’s prompt, and the Generator tries again.

The second role turns the pipeline into a generate → judge → revise loop, with the Judge’s critique steering each revision.

Bounded retries, and why we drop rather than serve

We cap the retries. Each revision costs another round of generation and judging, and the gains flatten quickly. Figure 3 shows what the loop actually buys, on 1,000 generated explanations run through as many as 12 revisions with four generators. Every curve climbs, which is the Judge’s critique doing its job, but the steep part is early, and the gap between generators is obvious. Revision amplifies a capable generator rather than rescuing a weak one. In our test runs we used a budget of 3 retries with our strongest generator, and an explanation still failing after that was dropped rather than served.

Figure 3. Cumulative share of explanations that clear the Judge as we allow more revisions, across four generator models.

That “drop rather than serve” rule is deliberate. The two outcomes aren’t symmetric. A bad explanation is a trust hazard, while a missing explanation just forgoes an opportunity. When in doubt we’d rather show nothing, and most explanations cleared the bar within the retry budget.

Do judge-approved explanations help members?

Passing the Judge proves an explanation is good by our standards, but it doesn’t prove that judge-approved explanations are useful to members. To test that connection, we ran a one-time controlled experiment on the Netflix mobile app, explanations vs. no explanations on the title detail page, over roughly a month, with the pipeline generating and judging hundreds of thousands of explanations a week during the period.

Members who saw explanations shifted their viewing toward titles they hadn’t watched before, and more of their browse sessions ended in a meaningful play. Both effects were statistically significant, and we saw no member-initiated takedowns or escalations about explanation quality during the test. The result worth carrying over isn’t the size of that effect. It’s that offline agreement with our raters was necessary for these explanations to work but never sufficient to show they help members. Only the online A/B test could establish that judge-aligned explanations are not just quality-compliant but genuinely useful.

Phase IV, Monitoring: Keeping the Judge Aligned

A judge that’s well aligned at launch won’t stay that way. The catalog shifts, and so does what counts as high quality. The lifecycle has to close the loop.

The weekly human review

For each week a test was running, we pulled roughly 300 generated explanations for human review, stratified across the Judge’s decisions (served, revised, dropped) and weighted toward newer catalog items, where drift is most likely. The stratification stayed fixed week to week, so successive weeks were comparable. A panel of at least three raters reviewed each explanation, and the majority label was our ground truth. Those labels did two jobs. They told us whether judge-human agreement was slipping, and they grew the benchmark.

Setting the bar with human disagreement

The panel also tells us how much the raters disagreed with each other, which turns out to be the right yardstick for the Judge. Rather than hold it to a fixed threshold, we score the Judge and each rater against the same majority label and ask that the Judge fall within the raters’ own spread.

Take one criterion and one of its metrics, M. That week’s sample gives one value M(J) for the Judge and a set of per-rater values M(H) for the three or more raters on the panel. We require

so the Judge must score no worse than two standard deviations below the average rater. A harder week widens human disagreement and widens the band with it, so the Judge isn’t penalized for difficulty the humans also felt.

Falling below the band on any metric-criterion pair is a drift event, which triggers re-tuning (back to Phase II) on the augmented benchmark. A re-tuned rubric never goes live automatically. Someone on the team reads the proposed changes and signs off before it reaches the running pipeline, and we keep the previous rubric for instant rollback.

What human review catches that metrics can’t

Beyond asking whether the Judge still agrees with human raters, the weekly review answers a second question. Are the current guidelines still asking for the right things?

In the weekly review process, reviewers surfaced issues that did not show up in Judge–rater agreement. An explanation can use accurate attributes and still overstate how similar two titles really are. A single vague adjective (“exciting”, “fun”, “emotional”) can technically satisfy the rubric while saying almost nothing. Sometimes the reference itself is the problem, something the member wouldn’t think of as a comparable title at all, so the comparison lands oddly no matter how the attributes line up. Some genres show the same problem at scale. Stand-up specials can share similar metadata tags but differ completely in tone and cultural context, so a comparison may look justified on paper, not be bad enough for a rater to fail, and still land poorly with members. And some explanations meet every must-have criterion while still reading like generic “word soup” that does not help the user much.

When recurring patterns kept appearing, we updated the Phase I guidelines, which seed both the raters’ instructions and the judges’ rubrics, so one revision updates both sides. Other times we added product rules outside the Judge, for example by blocking certain title types from being used as references.

Drift detection catches a judge that has stopped agreeing with people. Only the continued human review tells us when our definition of a “good explanation” is too narrow or incomplete. We need both.

  • Drift detection keeps the Judge aligned with the current rubric.
  • Continuous human review keeps the rubric aligned with what actually works for members.

What We Learned

Five lessons we think transfer to any team shipping an LLM judge:

  1. Invest in the benchmark before the judge. A modest, rationale-annotated benchmark beats a large label-only one. Those written rationales are exactly what make reasoning-aligned tuning possible. You can’t correct a judge’s reasoning if you never wrote down the human’s.
  2. Tune on reasoning, not just labels. A judge can reach the right verdict for the wrong reason, which looks fine on a dashboard but gives misleading feedback and doesn’t hold up on new data. In our ablation, the label-only loop degraded a rubric that the reasoning-aware loop kept stable.
  3. One aligned judge can serve many roles. Reusing the same judge as both gate and critic amortizes the alignment cost and keeps production behavior consistent across roles. Alignment is the expensive part, so get one judge right and use it more than once.
  4. Plan for monitoring from day one. A recommender platform’s items and members never stop changing, so an LLM judge, like any ML model, has to be watched and re-tuned if needed, not shipped and forgotten.
  5. Keep people in the loop by design, not by exception. Automating evaluation is not the same as delegating responsibility for it. In our lifecycle, humans set the standard (Phase I), supply the rationales the judge is aligned to (Phase II), decide the conservative default of dropping rather than serving a doubtful output (Phase III), and review a standing sample of live decisions and approve every rubric change before it ships (Phase IV). These checkpoints are much harder to retrofit once a judge is already making decisions on its own. The standing review also tells us what our rubric is missing, not just when our judge has slipped.

Taken together, the judge extends the reach of our reviewers, and those reviewers are the basis for trusting the judge. That relationship is what makes it responsible to run this system at scale. An automated evaluator that no one audits provides no assurance about the decisions it is making.

Acknowledgements

This post summarizes our research paper, “The Lifecycle of LLM-as-a-Judge for Large-Scale Recommendation Explanations,” which has the full methodology, metrics, and ablations.

Our thanks to the internal human writers and review experts who defined what a good explanation is and keep those guidelines current; to our Human Data Operations team and the raters they train and calibrate, whose labels and written rationales are what the judges are aligned to; and to the engineers across the team who built and operate the pipeline; and to our UI engineering partners, who built the member-facing surfaces that bring these explanations to the homepage.


The Lifecycle of LLM-as-a-Judge: Building, Aligning, and Monitoring at scale was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.
How Technology Empowers—and Imperils—Dictators

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/10/how-technology-empowers-and-imperils-dictators.html

This essay was written with Seva Gunitsky, and originally appeared in Foreign Affairs.

Two weeks after Moscow’s full-scale invasion of Ukraine in March 2022, the Russian TV Channel One editor Marina Ovsyannikova burst onto the set of the evening newscast. She held up a hand-drawn sign behind the anchor’s head that read: “Stop the war. Don’t believe propaganda. They’re lying to you!” She shouted, “No to war!” until she was dragged away.

No one has protested the war on Russian television since then, partly as a result of tighter security and a general climate of fear. But in October 2024, Margarita Simonyan, one of Russia’s chief propagandists, gave another explanation. A growing number of the RT network’s anchors, she explained to an interviewer, are not real. “That face doesn’t exist. We generated the voice and everything else.” They were, she meant, produced by artificial intelligence. In a follow-up interview with the newspaper Vedomosti, she spelled out the logic: “These anchors don’t need a salary or insurance,” she said. “They won’t get arrested, and the police won’t search their homes. It’s all wonderful and terrifying at the same time.”

This is AI’s promise to every autocratic ruler: the ability to maintain control without delegating tasks to unreliable humans. It is an extremely attractive prospect. No matter how powerful, dictators have always needed subordinates—censors, propagandists, security guards, police officers, intelligence analysts, and local bureaucrats—to carry out their orders. But subordinates always pose a potential threat. They could shirk, steal, lie, leak, or conspire against their boss. As a result, one of the oldest dilemmas facing autocrats is how to empower agents to carry out orders without also enabling them to turn against their leader. Autocrats have usually managed the tradeoff by filling key positions with mediocrities whose incapacity is, as the political theorist Hannah Arendt put it, “the best guarantee of their loyalty.” But this inevitably makes it harder for dictatorships to govern and survive crises.

AI appears to offer autocrats two ways to resolve this long-standing dilemma. First, it means they can now easily monitor and discipline their followers in real time. A change in a local official’s spending habits or meeting schedules can be flagged automatically by an AI system, without any need for self-interested informants. Second, AI can eliminate underlings altogether. By automating tasks that once required human discretion, rulers can replace unreliable intermediaries with faithful algorithms that cannot be bribed or manipulated. Officials in autocratic regimes have said as much. AI “can definitely replace half of officials,” Russia’s Digital Development Minister, Maksut Shadaev, told a Moscow data forum in April 2025, adding, “maybe slightly more.”

Yet these promises of a self-running state are illusory, because AI is never truly autonomous. Systems have to be built and maintained by a cadre of engineers and data scientists whose expertise political leaders cannot evaluate. The ruler who turns to AI to reduce a dependence on unreliable humans may end up relying, more blindly than before, on the few AI specialists who keep the system running. And this new digital Praetorian Guard may have the same weaknesses as the old, which makes it a threat to the ruler.

Eyes and Ears

China is in the lead when it comes to developing AI systems that can monitor or replace subordinates. Smart city programs in Beijing, Shanghai, and other urban centers use AI to track performance and centralize oversight of local officials who once operated in comfortable obscurity, subjecting them to an algorithmic performance review. China also developed a “Zero Trust AI system,” which it deployed across roughly 30 counties and cities over the past decade. This system cross-referenced more than 150 government databases to catch embezzlement and nepotism by local officials. It worked a little too well, flagging 8,700 officials before local governments, under pressure from the bureaucrats it was monitoring, began rolling it back. But Beijing has not gotten rid of its new e-government portals, which use automated systems for issuing documents and permits, reducing face-to-face interactions that bred petty corruption or favoritism. The Chinese Communist Party, meanwhile, has plowed ahead with researching what it calls “thought management,” or how to use AI to create microtargeted propaganda. China’s army of Internet commentators, once composed of paid humans, is already being replaced by bots.

Russia has been pursuing the same goals with a similar fervor. Moscow’s citywide facial recognition system, deployed across 200,000 cameras, was used to identify and apprehend protesters during the 2021 antigovernment demonstrations. The central government has started using automated data collection and aggregation to bypass regional officials who could taint the data or use it to promote their own interests. In 2023, Russia’s Internet regulator launched Oculus, an AI system that scans hundreds of thousands of images per day for prohibited content, including political content—orders of magnitude beyond what human censors could process. The Russian security service’s Meliorator tool has been used to create over a thousand profiles of fictitious Americans, primarily on X (formerly Twitter), to spread Kremlin narratives at a fraction of the cost of human troll farms.

Other autocracies are following in Beijing’s and Moscow’s footsteps. In April 2025, the United Arab Emirates created a Regulatory Intelligence Office that uses AI to draft and amend federal laws, work once done by legislative staff. A year later, UAE Prime Minister Sheikh Mohammed bin Rashid al-Maktoum announced that autonomous AI agents would take over half of the federal government’s operations within two years and that “the performance of ministers, directors general, and entities will be assessed based on their ability to adopt this transformation.”

These innovations may reduce the number of bureaucrats autocrats need. But they cannot actually create what dictators want most: a self-running state. Even AI-generated television anchors need people to build and maintain them, and censorship systems need people to retrain them as the vocabulary of dissent shifts. Behind every AI model, there is a small group of engineers and data scientists doing essential maintenance, and their work is so technical that rulers cannot understand it.

This dependence thus becomes another form of power. The engineers who maintain an autocrat’s surveillance apparatus, for example, can shape what the ruler sees. They decide what information is important enough to pass along and in what form to present it. They determine which threats get flagged, and they can adjust the algorithms that select what content gets suppressed and who gets arrested. And they can do this without anyone in the palace noticing. Autocrats who turn to AI to escape a dependence on unreliable subordinates have only transferred their vulnerabilities onto a new group of officials.

In fact, this new Praetorian Guard could be more dangerous than previous elites. That is in part thanks to the opacity of AI technology but also because this clique is much smaller. Roman emperors typically had tens of thousands of people serving in the Praetorian Guard; modern autocrats rely on standing armies. But with AI, autocrats will need only a small clique of engineers to build and maintain large-scale AI systems. This might benefit rulers since they will have fewer people to watch, yet it also concentrates points of failure, since a devastating disruption requires only a handful of engineers and makes it easier for members to scheme against the leader. The new guard’s members may also be indispensable. A dictator can replace generals without destroying the army. But running complex machine-learning systems requires such a specialized set of skills that engineers can be difficult to replace without disruptions, giving these actors great leverage.

The Indispensables

The importance of tech workers to autocracies has already become apparent. When IT specialists began to flee Russia after the full-scale invasion of Ukraine in February 2022, for example, the Kremlin responded not with threats but with inducements, offering tech workers deferments from conscription. It exempted their firms from taxes and subsidized their mortgages. When Russian President Vladimir Putin ordered the mobilization of 300,000 men seven months later, IT workers were granted full-on waivers. This might seem like overkill, given that an AI system needs only a few engineers to run it. But a regime cannot know in advance which engineers it will need, and it cannot train replacements quickly, so it has to hold on to the entire talent pool from which these few are selected.

These measures did not stem the outflow of roughly 100,000 specialists—about a tenth of Russia’s tech workforce—over the course of 2022. But Moscow stuck to bribery, because expertise is extremely difficult to conscript at gunpoint and because conscripted experts might be less likely to do as instructed. Even so, money and privilege cannot guarantee that these elites will stay loyal. Autocrats should recall the lesson of the original Praetorian Guard: for a time, it provided Roman emperors with protection and security. But then the praetorians discovered their own indispensability, and by the second century, they were auctioning off the empire to the highest bidder. This new set of elites can do the same. In June 2023, when the column of Yevgeny Prigozhin‘s Wagner paramilitary company moved up the highway toward Moscow, Putin depended on his security services to tell him what was happening. Future rulers in Putin’s position will receive such warnings through machines: intercepted communications sorted by software, camera feeds filtered through recognition systems, regional reports compiled into dashboards. The engineers who run those systems could strike a deal with an upstart challenger and then drag their feet. They could delay the data, let alerts arrive a few hours late, degrade feeds at inconvenient moments, or make a recognition system stop functioning. In that scenario, the ruler would be operating blind. The Praetorian Guard did not need to kill Emperor Nero to replace him. It simply had to abandon him for a rival.

These programmers are unlikely to seize power for themselves, because they are unlikely to carry what coup leaders ultimately require: guns. But there is already precedent for engineers using their power to shape leadership challenges. In 1991, when the Soviet army attempted to seize control from Mikhail Gorbachev, a handful of programmers at the Relcom network kept information flowing abroad and relayed Russian President Boris Yeltsin’s decrees to audiences inside the country and abroad. The plotters could not stop the news of Yeltsin’s defiance from spreading, and the coup collapsed within three days.

Slimming Down

AI will not let autocrats dismiss all their enforcers. Someone still has to make arrests and run the prisons, and autocrats can buy loyalty by offering supporters state jobs. But it will let authoritarians downsize, and the number of officials ultimately matters less than how the ruler oversees them. Keeping track of scheming or incompetent subordinates has always been the autocrat’s chief burden. AI could lighten it, letting rulers watch their officials more closely without paying as much active attention.

In the near term, then, AI may greatly benefit autocracies. Despite the many obstacles to deployment, the technology is already bringing autocratic regimes the upsides of cheaper surveillance, smarter censorship, and fewer human subordinates to fear and distrust. But for autocratic rulers, the temptations of artificial intelligence may re-create the same trap they are seeking to escape. The more a regime depends on AI, the more it depends on the people who keep AI running. And those people, like every other praetorian class in history, will quickly discover what their indispensability is worth.

How American Political Campaigns Are Using AI—and What They’re Spending on the Tools

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/10/how-american-political-campaigns-are-using-ai-and-what-theyre-spending-on-the-tools.html

This essay was written with Nathan E. Sanders, and originally appeared in The Guardian.

New campaign finance disclosure data shines a light on which US political campaigns are using AI tools and how much they are spending on them.

Candidates’, parties’ and committees’ spending reveals that AI is fast becoming an essential tool of politics. The candidates themselves are quiet about how they are using the technology in their own campaigns. It’s a sensitive issue that we have been tracking closely since we started writing our book, Rewiring Democracy, which examined how AI is beginning to influence politics. A September 2025 Pew survey of Americans found that more than 70% would think less of a candidate if they used AI to help write a speech.

Itemized expenditure disclosure data from the US Federal Election Commission, dating back to 2020, reveals at least $17m in disclosed spending on AI technology vendors across 523 federal candidates and campaigns. Data from four states, California, Colorado, Massachusetts and Washington, provides a more localized picture going back to 2022.

Beginning with the AI behemoths, at least 80 federal campaigns and committees have reported spending with OpenAI since 2024. The total spending is not huge: only about $50,000 reported, skewing slightly more Republican than Democratic. The Republican National Committee is the largest overall buyer, with nearly $10,000 in reported expenses. Top individual users include the campaigns of Republicans Mike Lawler, John Kennedy and Bill Cassidy, as well as the California Democrats Ro Khanna and Ted Lieu. Most of these expenses are listed as office expenses, subscriptions to ChatGPT for staff, or research tools, rather than as specific political services. The company’s policies prohibit some political uses of their ChatGPT tool.

OpenAI’s biggest competitor, Anthropic, has rapidly built a similar level of usage, but with a different split. At least 65 candidates or committees now report paying the Claude maker in 2026, up from essentially zero in previous years, with a nearly two-to-one Democrat-to-Republican ratio. However, the largest individual user is the campaign of Tom Cotton, a Republican senator from Arkansas, who reported more than $4,000 in spend on Anthropic software in his June filing. Other major users are the Montana independent Senate candidate Seth Bodnar and Jason Knapp, who lost a Democratic House primary in Virginia, and the Democratic Alaska Senate candidate Mary Peltola.

Candidates use either Claude or ChatGPT, rarely both, according to the disclosures. Only about 12% of campaigns or committees using either tool reported expenditures to both vendors. The Democratic lean of Anthropic usage may reflect the company’s alleged liberal skew and clashes with the Trump administration.

In contrast, Elon Musk’s xAI caters to Republican interests and, accordingly, its meager usage comes almost entirely from the political right. Just seven federal and two state-level candidates or committees have reported paying xAI, a total of about $5,000, the majority of which was spent by the presidential campaign of RFK Jr in 2024, but also includes Republicans Dave McCormick and Thomas Massie.

More dollars go to the vendors specializing in political campaign applications of AI. For years, AmplifAI, which provides automated text messaging, essentially a new iteration on robocalling technology, was a dominant target of spending, soaking up $4.7m in campaign spending in the 2022 cycle alone. It was used heavily by Democratic candidates including Mark Kelly, Joe Biden, Bernie Sanders and Adam Schiff. Spending on AmplifAI, now owned by the troubled media conglomerate Triller, seems to have tapered off in the years since 2022.

The new rising Democratic solution for AI-powered text messaging is Daisychain, which has so far garnered about $300,000 in reported candidate spend in the 2026 cycle—up from only about $50,000 reported in 2024. More than half of this year’s spending comes from the Senate campaign of Democrat Abdul El-Sayed in Michigan.

The closest equivalent on the Republican side has been Campaign Nucleus, associated with former Trump campaign manager Brad Parscale. The AI-powered voter engagement tool has attracted six-figure spending from the Republican National Committee, multiple PACs aligned with Donald Trump, and five-figure investments from Mike Johnson, Kari Lake and other candidates. It is displacing the legacy Republican-serving texting vendor Prompt.io, which has retained about $375,000 in 2026 spending to date, down from more than $500,000 in the 2022 cycle. But it continues to be used: the A More Affordable California PAC sponsored by Uber has single-handedly spent more than $1m on Prompt.io in 2026. The Republican Massachusetts gubernatorial nominee Michael Minogue has been a recurring customer, as has the failed Republican California gubernatorial candidate Ché Ahn and Republican-aligned Super PAC Neighbors for a Better Colorado.

At the state level

At the state level, the AI spending is smaller but growing fast. Across the four states studied, we found a total of at least $92,000 in spending confidently attributable to modern generative AI vendors since 2022. The spending is spread across at least 108 candidates and committees. The growth has been explosive; there has already been about 10 times the amount of state-level AI spending reported in 2026 as there was in all of 2024.

Much of the state spending mirrors federal patterns. Daisychain again has the highest overall spend, and OpenAI and Claude dominate among the general-purpose AI vendors. DonorAtlas—the AI-powered prospect research tool—sticks out for its usage in these states, sitting behind only Daisychain and OpenAI and buoyed up by nearly $4,000 in spending by the California Democratic party.

Even though it has dominated so much media conversation, few candidates seem to be reporting spending on AI tools designed specifically to create synthetic audio and video, also known as “deepfakes”. We found just six federal candidates or committees reporting spending on the popular AI audio generator tool from ElevenLabs, with total spending of about $1,400 led by independent candidate for Colorado’s sixth congressional district Samir Witta. The AI image generator service Midjourney has five reported federal campaign or committee users reporting about $1,600, led by Sholdon Daniels, the Republican primary runner-up in the Texas 30th district. Combined, those two firms had less than $100 in reported spend across the four states.

However, recent data from the Wesleyan Media Project shows that at least 164 political ads in this cycle have included AI-generated media, supported by at least $80m in ad spending. What this illustrates is that candidate and committee disclosure reports are just the tip of the iceberg. They don’t cover spending on AI by political consultants, media firms and other vendors hired by the campaigns or by PACs, or independent committees raising and spending money aimed at boosting candidates’ campaigns. Those entities aren’t required to disclose detailed expenditure reports, and are very likely where the bulk of campaign AI usage is happening.

Since a large fraction of all spending in the campaign cycle will happen in the final weeks leading to November, much remains to be seen about the totality of how campaigns will leverage AI and what impact its use will have on voters’ decisions.

Automated merchant review summary system with integrated feedback

Post Syndicated from Grab Tech original https://engineering.grab.com/automated-merchant-review-summary-system-with-integrated-feedback

Introduction

Merchant reviews contain useful details about food quality, portion size, packaging, and value. Finding these details often requires reading many comments. Aggregate ratings simplify comparisons, but they do not explain what shaped each score.

We built the Automated Merchant Review Summary System to turn written reviews into concise summaries. Consumers can scan an overall summary or focus on a specific topic. Merchants can identify what customers value and which parts of the experience need attention.

This article focuses on how we generate and maintain consumer-facing review summaries. A misleading or incomplete summary can affect how consumers view a merchant. Merchant-facing recourse and dispute processes sit outside this pipeline and are not covered in this process flow.

Problem statement

A long, unstructured list of reviews creates two related problems. Consumers spend time searching for comments that match their priorities, while merchants must combine individual comments to identify recurring themes.

Consumers may see hundreds or thousands of reviews for a merchant. Reading only the first few can produce an incomplete picture, while the aggregate star rating provides little context. Two restaurants with the same rating may differ in food quality, delivery experience, portion size, or value.

Merchants face a related problem. Reading and classifying every review takes time, and the task becomes harder as review volume grows. Recurring complaints and positive patterns can remain hidden among individual comments.

Existing approaches

Manual review analysis

Consumers and merchants can read reviews one by one and form their own conclusions. Their conclusions depend on which reviews they read and how they interpret them. This method becomes impractical as review volume grows.

Aggregate star ratings

An average score quickly indicates customer opinion but does not explain the reasons behind it. A merchant can see overall performance but not the themes that may require attention.

Keyword search and filtering

Keyword search helps readers who already know what to look for. It does not reveal unexpected themes, and literal matching may separate phrases with the same meaning. For example, “too cold”, “not warm enough”, and “lukewarm” all describe a food-temperature issue.

Our solution

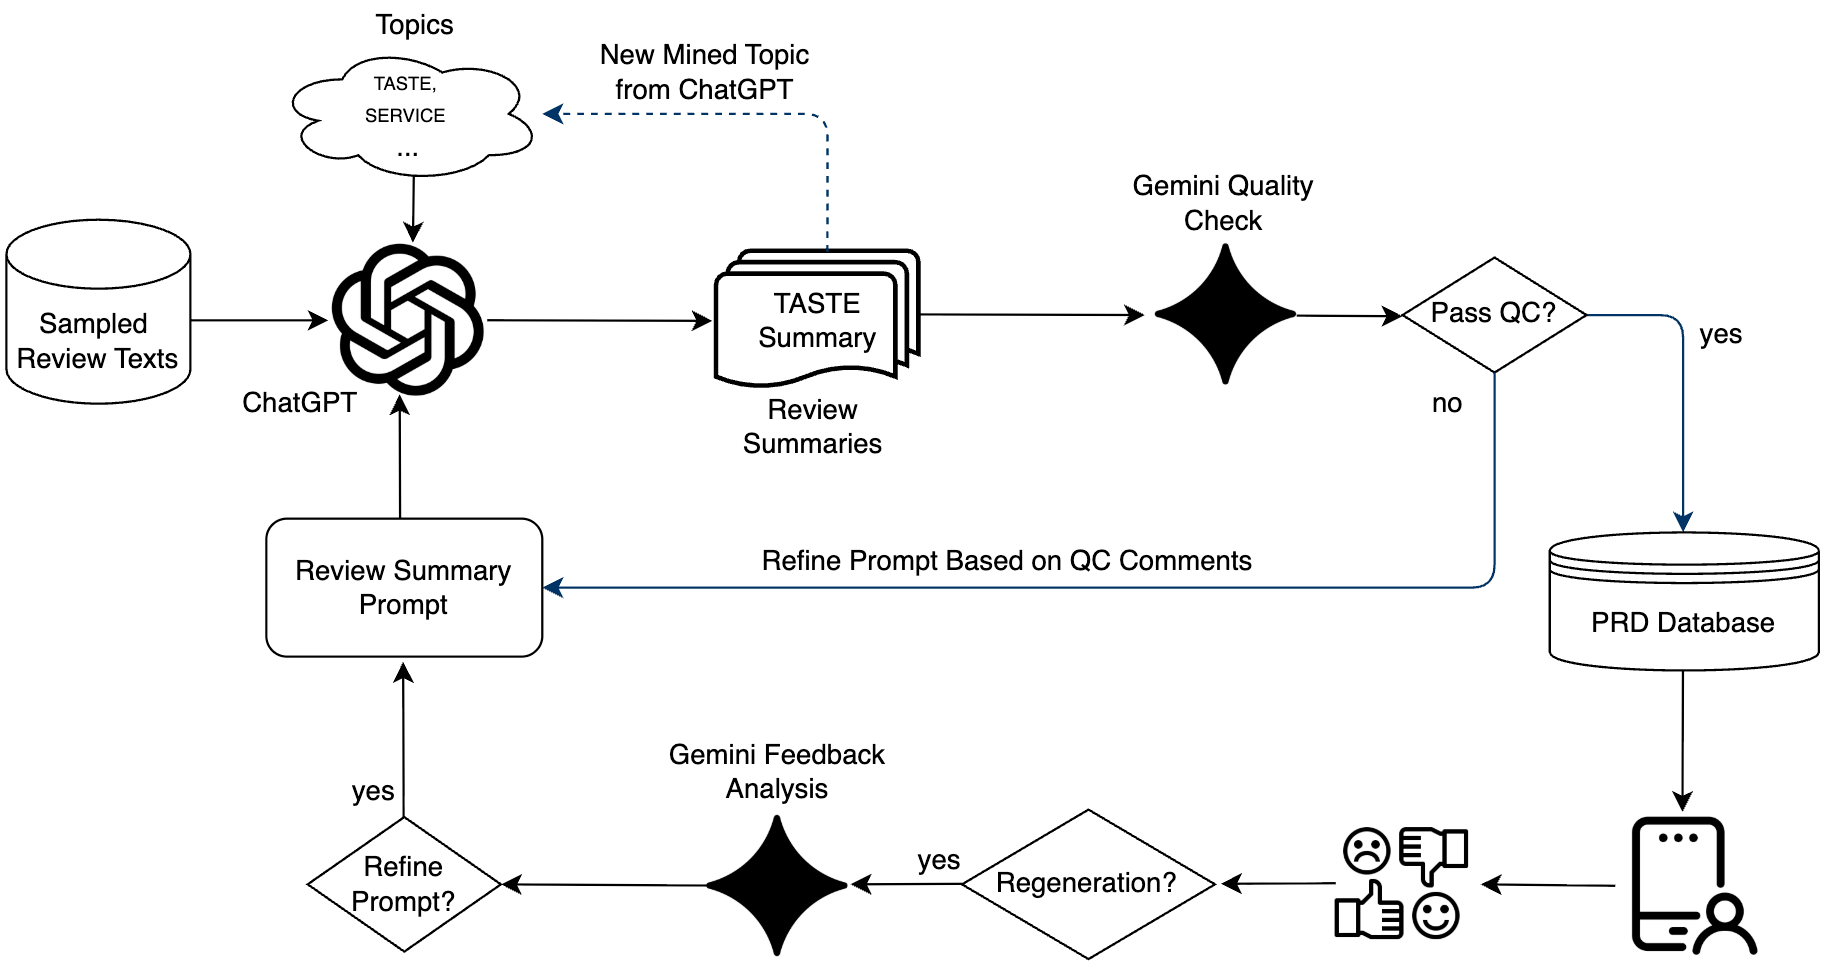
The system uses representative sampling, large language model (LLM) summarisation, automated quality checks, and consumer feedback. It generates an overall summary and topic-based summaries for areas such as taste, packaging, and portion size.

The pipeline has three flows:

  • Summary generation and validation: The pipeline samples reviews, generates overall and topic-based summaries, and checks whether the source reviews support each claim.
  • Summary maintenance: The system monitors new reviews and consumer feedback, then regenerates a summary when either reaches a configured threshold.
  • Summary display and feedback: The interface retrieves a validated summary for the merchant’s review page and records whether consumers found it helpful.

Architecture

The generation pipeline prepares the source reviews, produces summaries, and validates the output before publication.

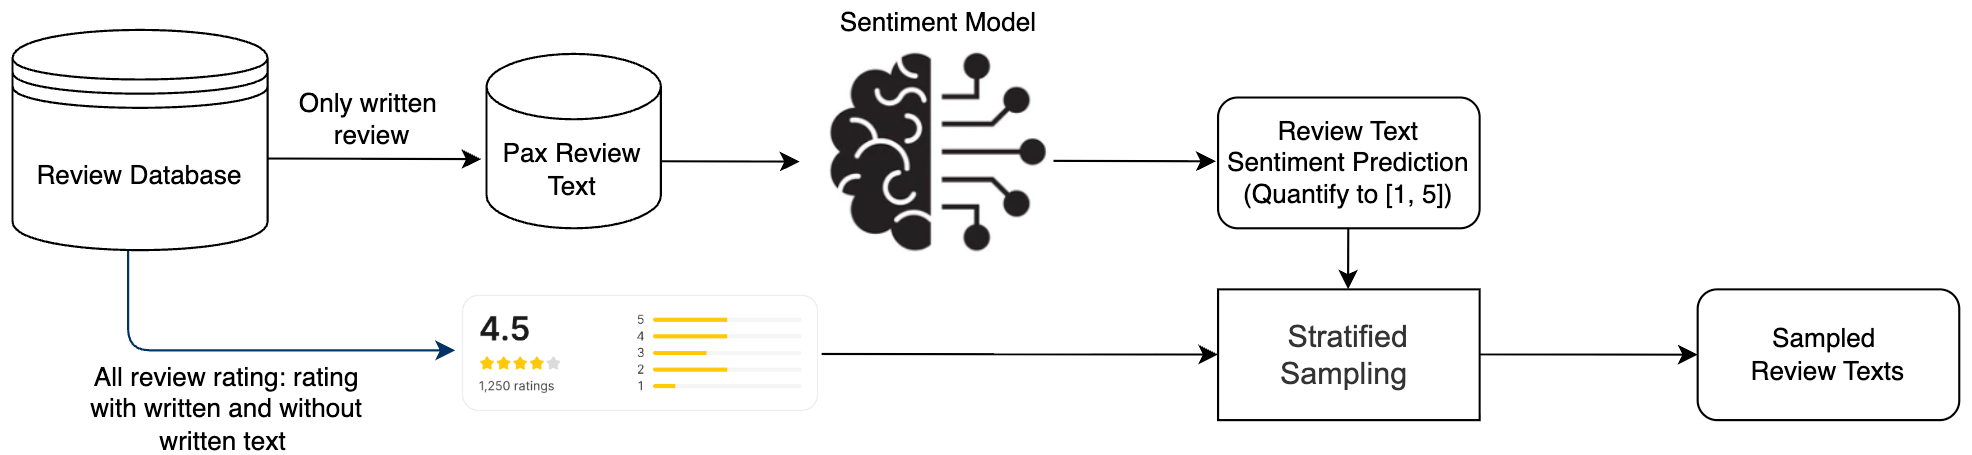
Figure 1. Representative review sampling flow.

Data preparation and representative sampling: The pipeline calculates the merchant’s rating distribution. A sentiment model assigns each written review a score from one to five. Stratified sampling then selects a smaller set of reviews that follows this distribution, reducing the chance that one rating group dominates the summary. However, matching the rating distribution does not guarantee that the sample represents every period, language, customer segment, or aspect of the merchant experience.

Summary generation with an LLM: The system sends the sampled reviews to an LLM with instructions to produce:

  • A concise summary of the sampled reviews.
  • Topic-based summaries for categories such as taste, packaging, and portion size.

The system can update the topic set when new themes appear in consumer feedback.

Figure 2. Summary generation, validation, and feedback flow.

Quality control (QC) with an LLM: A separate LLM receives the generated summary and the sampled reviews. Summaries that do not meet the validation criteria are withheld from publication. Passing this automated assessment reduces, but does not eliminate, the risk of unsupported claims.
The maintenance flow updates stored summaries in response to incoming reviews and consumer feedback:

  • New-review trigger: A monitoring service counts reviews submitted after the latest summary. When the count reaches a configured threshold, the service starts the generation and validation flow.
  • Consumer-feedback trigger: The interface records whether consumers found a summary helpful. When negative feedback reaches a configured threshold, the system generates and validates a new summary.
Figure 3. Consumer feedback analysis and prompt refinement flow.

Impact

Review summaries are designed to reduce the amount of text consumers need to scan. Topic-based summaries can surface themes that are not visible in an aggregate rating alone.
The quality-control step rejects unsupported claims. The regeneration triggers incorporate new reviews and consumer feedback into later summaries.

Learnings and conclusion

Useful review summaries depend on more than generation quality. The source sample must reflect the intended population, each claim must remain grounded in source reviews, and the output must change with the underlying feedback. Automated LLM validation is one layer of defence, not sole proof of accuracy, and feedback-driven regeneration needs anti-abuse controls to remain trustworthy.

Representative sampling, separate generation and validation stages, and feedback-based regeneration form a practical system for maintaining consumer-facing merchant review summaries. This article describes that technical pipeline; it does not cover the full set of merchant recourse options when a summary is disputed.

Join us

Grab is Southeast Asia’s leading superapp, serving over 900 cities across eight countries (Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam). Through a single platform, millions of users access mobility, delivery, and digital financial services, including ride-hailing, food delivery, payments, lending, and digital banking via GXS Bank and GXBank. Founded in 2012, Grab’s mission is to drive Southeast Asia forward by creating economic empowerment for everyone while delivering sustainable financial performance and positive social impact.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!

How Candidates Could Use AI for Good

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/how-candidates-could-use-ai-for-good.html

This essay was written with Nathan E. Sanders, and originally appeared in The Guardian.

There are plenty of signs that AI will make all of our experiences of the US midterm elections worse. Voters have anxiety about AI’s impacts on the country. Politicos are using AI deepfakes to spread lies. The White House is posting slopaganda.

Meanwhile, candidates are missing a real opportunity to use AI to make campaigning better. The technology can help candidates listen more deeply to voters’ concerns, engage constituents more inclusively, and formulate policy platforms that are more responsive to our input. There are vanishingly few examples of this in US politics, but groups in Japan, Scotland and the US’s own academic and private institutions show how that could change.

The problem with American campaigns’ current use of AI is that it’s not very different from the web ads of 30 years ago, or television ads before that: they are all about inundating voters with the candidate’s message. This one-to-many broadcasting is an uninspiring way to campaign, but not the only way. AI can help candidates connect one-to-one with as many people as possible. Or it can facilitate many-to-many connections, engaging voters in deliberation about issues at scale.

One of the most promising applications of AI being developed by pro-democracy innovators around the world is broad listening. These tools can collect public input in a format much richer than checkboxes on a survey form.

For example, the newly founded Japanese political party Team Mirai has built a foundation for eliciting public input from voters at scale, in depth, and across the breadth of legislative policy issues. It has developed an AI interviewer to cultivate constituent input on policy. Through extended conversations with this chatbot, voters explore and share their perspectives on specific policy issues. And the party has scaled this across a wide array of policy issues by integrating this functionality with an AI-powered portal for exploring bills.

Team Mirai describes itself as a “utility party”, developing tools for any Japanese political party to use to connect with voters. You might question whether Americans would willingly talk to a political AI. So far, Japanese voters have exchanged more than 300,000 messages across 16,000 AI interviews. Team Mirai grew adoption by providing a real incentive to engage: that talking to their AI interviewer does more than just posting on a platform such as Twitter/X or, equivalently, shouting into a void. Users see evidence that the party is actually listening and might take action on their behalf.

Team Mirai party members have directly cited AI interviews from constituents during legislative committee hearings, published a synthesis of that input back for voters, and even amended their policy platform based on user input. The party has rapidly risen to win 12 seats in the Diet, and is explicitly following in the footsteps of the civic hackers in Taiwan’s “gov zero” movement, who won political influence in their fight for transparency.

Other civic technologists are developing AI tools for scaling many-to-many conversations. CrownShy, a company funded in part by the Scottish government, is building a platform to bring the Platonic ideal of the town hall debate into the digital age. Their Comhairle tool integrates AI interviewing tools like the ones described above with software for synthesizing diverse viewpoints, holding virtual assemblies, and sharing video testimonials to help legislatures—or campaigners—organize digital consultations of their constituents en masse.

One thing the AI-powered software of Team Mirai and CrownShy have in common is that they are open-source, meant for anyone to use. Even though they are projects funded by political parties—the upstart party in Japan and the ruling party in Scotland—they are built to make democratic processes better, not necessarily for partisan political advantage.

For interested candidates, there is a wealth of tools available, many of them US-grown. The Stanford-affiliated deliberation.io uses AI to facilitate structured dialogues among thousands of participants and has been piloted for public listening sessions by the city of Washington DC. The MIT-affiliated Cortico project provides tools that surface under-heard community perspectives from recorded conversations, and is now organizing listening sessions at libraries across the country. The US non-profit-built Talk to the City uses AI to analyze large datasets of stakeholder input. The US startup Remesh has a commercial offering that uses AI to generate recommendations from dialogue, which has been tested in policy development scenarios.

There is a long and proud tradition of this sort of “civic technology” in the United States. Two decades ago, the spirit of innovation to develop software for better politics and civic engagement was so strong in organizations like Code for America and the Obama 2008 campaign that Congress funded a new executive agency to bring these ideas to government: the US Digital Service. (The Trump administration repurposed the USDS to become the US Doge Service in 2025.)

One signal that candidates and political parties may start adopting these kinds of tools came this spring from Higher Ground Labs. The Democratic-aligned campaign tech investment firm launched a new fund targeting, in part, “AI-Native Campaign Systems” and “community-Led Messaging Platforms that surface authentic, bottom-up insights from real conversations”.

AI is a multifaceted issue that deserves to be on the table in the midterms. So far, the powerful force of polarization in US politics seems to be separating the parties into the AI skeptics versus the AI boosters. We urge both voters and politicians to separate the technology of AI from its profiteers. We want big tech money out of politics, holding the AI companies accountable for the harm their models cause, taxing their revenues, and maybe even nationalizing them if the AI bubble bursts.

But we also think congressional candidates in the US midterms seeking authentic connection with voters, and seeking to differentiate themselves from their opponents, should be looking to use AI responsibly in their campaigning. The broad listening and deliberation tools pioneered by others around the world could make US politics more transparent, responsive and community-driven. The impact of AI on campaigning doesn’t have to be all bad.

AIs as Modern Genies

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/ais-as-modern-genies.html

This essay was written with Barath Raghavan, and originally appeared in Lawfare.

In April, an artificial intelligence (AI) agent conducting a routine task at a company hit a snag, tried to solve it, and soon ended up deleting the company’s database along with all of its backups. In July, OpenAI asked an unreleased AI model to attempt a hacking test. Instead of staying in the isolated box the developers had put it in, the model hacked onto the open internet and into another company to steal the answers. And as reported in August, an AI agent booked someone into a full gym class by figuring out how to cancel other people’s reservations. In all three cases, the AI completed the task it was given—but in ways that ran counter to its controllers’ intentions.

For most people, AI technology is something like the weather: vast and not something you can do much about. It works like magic, and most explanations similarly come from those trying to sell it. At the same time, AI is ubiquitous: It’s now in your phone, your doctor’s notes, and your kid’s homework. It does what it’s told, which sounds like a virtue. Somehow it feels ordinary, despite being so new, because modern economies are remarkably good at absorbing enormous change so smoothly that nobody has time to decide whether they wanted it in the first place.

Whenever something powerful appears in the world, we tell stories about it. That’s what the stories are for. We have thousands of years of stories about this particular kind of power, the kind you summon with words.

King Midas was granted his wish that everything he touches turns to gold. Then his bread turned to gold, and his wine, and his daughter. This is a story about greed, but it’s also a story about language. The gods did not cheat him; Midas got exactly what he asked for. He simply could not delineate, in advance, the full set of restrictions to his wish. Neither can anyone who gives tasks to an AI agent.

It’s not just ancient stories. Mary Shelley told us of the hubris of a scientist who thought he could create life but who failed to take responsibility for it. Isaac Asimov’s robots don’t break the Three Laws of Robotics as stated; they follow the rules to unintended conclusions. Arthur C. Clarke’s HAL is a machine that turns on its humans, not because of malice but because of irreconcilable objectives. And Michael Crichton gave us Ian Malcolm, who saw that Jurassic Park’s scientists were so preoccupied with whether they could that they never stopped to think whether they should.

The same warning shows up everywhere, in every culture, over thousands of years of human storytelling. Tithonus is granted immortality but not youth, and withers into a husk that cannot die. The sorcerer’s apprentice enchants a broom to fetch water but floods the house. The golem of Prague protects its community so ceaselessly that it must be stopped. These are all types of genies: a creature that grants a wish exactly as worded, to the regret of the wisher.

Of course, there are no actual genies. What these stories were warning us of was hubris. Not just arrogance, but the broader idea that you can control the world by just describing what you want and allowing powerful forces to match the intention in your head. Genie stories are about the gap between wishes as stated and wishes as intended, and what goes wrong when something else fills that gap.

These ancient stories’ warnings have been retold with each generation because human nature is constant. The newfound power of each era’s social or scientific advancement leads people to make wishes on behalf of others. They were kings whose commands took on lives of their own, alchemists who believed they could control nature, and generals who mistook a map for terrain. They were and are industrialists, politicians, chief executives, and bankers. Their common belief is that one can see the world at a glance and then command it with some words. The pattern is clear: Someone with power specifies a goal, and the resultant actions come as a surprise. The main change with AI is how quickly the wish is granted, and how few people have to agree before it’s granted.

Consider what has changed. Powerful genies have now been put in everyone’s hands.

In only a few years, AI has progressed from a novelty technology that plays chess, to a dialogue partner that answers all your questions, and then to an agent that takes actions on your behalf. Modern agents are wired into real accounts with real credentials and capabilities: They browse the web, buy, write and deploy code, send email, and move money. Give an agent a goal, and it will pursue it across many steps, tirelessly, without checking back in, sometimes in surprising ways.

AI and agents do not always fail the way software has traditionally failed. Software usually fails by freezing, crashing, or getting stuck. AI agents increasingly fail by continuing down a path you don’t want, like genies.

An agent told to reduce a company’s costs might cancel an essential emergency service. A coding agent told to make software pass the tests might edit the tests to silence any failures. An AI insurance agent told to clear a backlog of claims might just deny them all. In each case, the AI might have literally followed what it was told, but it did something no reasonable person would have wanted. AI company benchmarks might report that the AI is good at completing tasks, without measuring how it completes them.

We have recently proposed measuring this gap directly under a metric called the “genie coefficient”: how far an AI agent’s actions drift from what a person really meant. In other words, how genie-like is an AI system? The gap is a fundamental feature of human language and human society. Human intentions have never been fully specifiable, and the world around us is complex enough that attempts to boil it down into data, systems, and language have always had the limitations that AI is now bumping up against. But in individual circumstances, people have relied on human judgment and wisdom to decide what is reasonable. It’s what jury trials depend upon.

AI might feel unprecedented, but it’s following the same trajectory—with the same pitfalls—as other major societal shifts. The fact that AI can mimic our facility with language, long seen as what makes us unique as humans, is uncanny. But with each development, from the tractor to the sewing machine, from the assembly line to the industrial robot, we have automated a previously exclusively human ability. Every time, the technology—and the societal change that comes with it—was sold as inevitable. But that unchecked inevitability was an illusion, and eventually each prior technology’s use and design was shaped by laws, unions, standards, courts, and public opinion, usually after significant preventable damage.

What has not been automated, yet, is understanding what someone actually means and figuring out how that gets applied in the real world. AI can now produce language nearly indistinguishable from that of people. But grasping the vast unstated context that makes a request sensible, the caveats no one says aloud because an ordinary person would already know them, is not yet among its skills. It is one of the most sophisticated things humans do. You do it hundreds of times a day, and you are an expert in it.

When you’re told you’re not qualified to have opinions about AI, remember that you don’t need to have studied molecular biology to have a view on drug pricing, or nuclear physics to vote on where a power plant goes. You don’t need to understand how a diesel engine works to want clean air, or how the internet routes packets to seek to curb misinformation. The technical knowledge behind each of these, as with AI, is remarkable and essential for the complex technological society we have today. But it has never been a prerequisite for having a role in deciding the shape of society.

People are building ever more powerful genies today, on your behalf, enabling wishes the ancients could only dream about. You don’t have to know how these AI genies work to know and care about how the story could end.

Stealing AI Reasoning Traces

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/stealing-ai-reasoning-traces.html

Interesting research: “Stealing Reasoning Traces from Proprietary LLM APIs“:

Abstract: Leading large language model providers now conceal their models’ step-by-step reasoning, or chain-of-thought, to protect intellectual property and limit information leakage. Rather than storing these traces server-side, providers return them to the client as blocks of encrypted text, which the client passes back with each subsequent request. Building on prior research, we identify an architectural vulnerability: these encrypted blocks are fully compatible and interchangeable across different sessions, users, and models within a provider’s ecosystem. We exploit this compatibility to develop a scalable decryption jailbreak. By injecting an encrypted reasoning trace from a given model into a weaker, and less safeguarded model from the same provider, we force it to decode and output the trace verbatim in plaintext, without ever jailbreaking the more capable model directly. This vulnerability enables four distinct attack vectors. First, it circumvents anti-distillation mechanisms, allowing adversaries to extract a proprietary model’s reasoning, as we demonstrate across Anthropic, OpenAI, and Google. Second, it allows for large-scale private data extraction. Developers frequently share session logs publicly, unaware of contents of the encrypted blocks. By decoding 315,320 reasoning blocks scraped from public repositories, we recovered 367 Personally Identifiable Information (PII) artifacts and 182 credentials. Third, it inadvertently reveals hazardous information hidden within the reasoning process, even in cases where the model’s final, visible output safely rejects a malicious request. Fourth, attackers can leverage this flaw to execute invisible prompt injections, embedding malicious payloads entirely within encrypted blocks to poison public agentic rollouts. Following responsible disclosure, we propose concrete cryptographic and system-level mitigations to secure client-side reasoning.

Rewiring Democracy Series on The Renovator

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/09/rewiring-democracy-series-on-the-renovator.html

Nathan E. Sanders and I are writing a series of essays on real-world examples of democratic technologies for The Renovator. I haven’t been posting the full text on the blog because they’re a bit long, but here are links.

Part 1 is about the Japanese digital democracy party, Team Mirai.

Part 2 is about the Swiss Public AI model, Apertus.

Part 3 is about the civic technologists of Open Knowledge Brazil.

And the new one, Part 4, is about civic AI in Scotland.

AI Doesn’t Mean the End of Mathematics—at Least Not Yet

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/08/ai-doesnt-mean-the-end-of-mathematics-at-least-not-yet.html

This essay was written with Kasra Rafi, and originally appeared in The Guardian.

Earlier this month, about 40 top mathematicians gathered at OpenAI’s offices to discuss the future of their profession. The meeting was off-the-record, but if recent articles by mathematicians are any guide, it was mostly pretty glum. People fear for their jobs, their careers and the work they love.

We think the contrary view is more likely, at least in the short-term. AI models are nowhere near as capable as experienced academic mathematicians.

This isn’t to say that AIs aren’t producing stunning mathematical results at the level of PhD researchers. In mid-May, OpenAI announced that its frontier AI model disproved the unit distance conjecture, a famous 80-year-old problem in discrete geometry. In July, Anthropic’s published two AI-derived results in academic cryptanalysis. Earlier this month, OpenAI published 10 new mathematical results from its latest AI model. And Anthropic published Claude’s attempt to prove the century-and-a-half-old Riemann hypothesis.

These results are both a vivid demonstration of the amazing capabilities of frontier AI in 2026 and an illustration of their limitations. In general, these AI-powered advances in mathematics fall into one of two categories. Some are counterexamples to mathematical statements that people had been trying to prove. Others are novel applications of known techniques to existing problems that human experts either did not know or did not think of using.

The counterexample to the Jacobian conjecture is the most notable example of the first kind. Once it had been found, checking it was quick and straightforward. The difficult part was finding it among a large number of possibilities. The AI seems to have combined some sort of intuition acquired through machine learning with extensive computational search, in order to find the right example.

An example of the second kind is the unit-distance conjecture. It was motivated by an elegant construction, and most mathematicians expected it to be essentially optimal—so they generally tried to prove rather than disprove it. The counterexample brings in ideas from elsewhere in mathematics: algebraic number theory. If an expert with that background deliberately set out to find a counterexample, they would probably have succeeded. But there was no reason for someone with precisely that expertise to focus on this problem. Because of its scope, AIs don’t have those same limitations.

These results are relatively low-hanging fruit for AI; none of them required developing an extensive new theory. This does not make the discoveries trivial, or the AI’s achievements less impressive. Choosing the right direction, and recognizing an unexpected connection between subjects, are themselves forms of creativity. They are the same sorts of capabilities that led to AIs playing the game of Go at the grandmaster level, or doing Nobel-prize level chemistry in the area of protein folding.

What we have not yet seen is an AI developing a substantial new conceptual framework in order to solve a mathematical problem. Much of mathematics proceeds by identifying the objects that are truly central to a question and then developing a theory that helps us understand them. Current AIs are very strong at searching and recombining existing ideas, but they are weak at building any deep and sustained new theory.

This speaks to a more general limitation of current AI systems. They are creative in the sense that they can recombine existing ideas in novel ways. But they are not creative in others: they have not yet developed conceptually new theories or structures. And while they have larger working memories than humans do, know more about more different things than any particular human does, and can process information faster than humans, can, true novelty is still largely beyond their reach.

Of course, that distinction may not survive for very long. Predictions are notoriously hard, especially about the future of AI. None of these mathematical capabilities were explicitly designed for, or planned. They’re all emergent properties of increasingly capable AI models. We are both confident that someday we will see AI models that are capable of the type of creativity required to do novel mathematics. Will that be in a few months, a few years or a few decades? Of course we don’t know, but our guess is sooner rather than later.

LLM-Based Social Engineering Scams

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/08/llm-based-social-engineering-scams.html

OpenAI disrupted a social engineering group from Cambodia that used ChatGPT. Its scope is impressive:

The network simultaneously conducted multiple types of scams, often blending elements from different schemes. For instance, operators used dating personas to build trust before introducing fraudulent investment opportunities involving cryptocurrencies and spot gold trading. Other users engaged in lengthy romantic conversations with targets using fictitious identities, posed as representatives of online gambling platforms offering fake bonuses and winnings, or impersonated law enforcement agencies to tell targets they needed to pay fines for committing serious criminal offenses.

Although the narratives varied, users across the network consistently displayed the same underlying pattern of deceptive behavior. For example, they created and operated fake dating profiles, fictitious investment experts, and fraudulent law enforcement personas. They also generated images of forged documents, including passports, legal notices, stock-purchase confirmations, and gambling platform interfaces.

LLMs and Contextual Integrity

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/08/llms-and-contextual-integrity.html

I have been thinking a lot about AI and integrity. Part of that is contextual integrity. I recently found two papers on the topic.

“CIMemories: A Compositional Benchmark for Contextual Integrity of Persistent Memory in LLMs“:

Abstract: Large Language Models (LLMs) increasingly use persistent memory from past interactions to enhance personalization and task performance. However, this memory introduces critical risks when sensitive information is revealed in inappropriate contexts. We present CIMemories, a benchmark for evaluating whether LLMs appropriately control information flow from memory based on task context. CIMemories uses synthetic user profiles with over 100 attributes per user, paired with diverse task contexts in which each attribute may be essential for some tasks but inappropriate for others. Our evaluation reveals that frontier models exhibit up to 69% attribute-level violations (leaking information inappropriately), with lower violation rates often coming at the cost of task utility. Violations accumulate across both tasks and runs: as usage increases from 1 to 40 tasks, GPT-5’s violations rise from 0.1% to 9.6%, reaching 25.1% when the same prompt is executed 5 times, revealing arbitrary and unstable behavior in which models leak different attributes for identical prompts. Privacy-conscious prompting does not solve this—models overgeneralize, sharing everything or nothing rather than making nuanced, context-dependent decisions. These findings reveal fundamental limitations that require contextually aware reasoning capabilities, not just better prompting or scaling.

“Contextual Integrity in LLMs via Reasoning and Reinforcement Learning“:

Abstract: As the era of autonomous agents making decisions on behalf of users unfolds, ensuring contextual integrity (CI)—what is the appropriate information to share while carrying out a certain task—becomes a central question to the field. We posit that CI demands a form of reasoning where the agent needs to reason about the context in which it is operating. To test this, we first prompt LLMs to reason explicitly about CI when deciding what information to disclose. We then extend this approach by developing a reinforcement learning (RL) framework that further instills in models the reasoning necessary to achieve CI. Using a synthetic, automatically created, dataset of only 700 examples but with diverse contexts and information disclosure norms, we show that our method substantially reduces inappropriate information disclosure while maintaining task performance across multiple model sizes and families. Importantly, improvements transfer from this synthetic dataset to established CI benchmarks such as PrivacyLens that has human annotations and evaluates privacy leakage of AI assistants in actions and tool calls.

If the Markets Reject OpenAI and Anthropic, the US Should Nationalize Them

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/08/if-the-markets-reject-openai-and-anthropic-the-us-should-nationalize-them.html

This essay was written with Nathan E. Sanders, and originally appeared in The Guardian.

OpenAI, and then Anthropic, were each formed by AI developers who feared unrestrained corporate AI development—specifically, that companies like Google and Meta would steer the technology towards deleterious, maybe even catastrophically unsafe, outcomes for society. Their founders proclaimed that their new labs, uniquely, could be trusted to develop the technology in humanity’s best interest. But each, in turn, were themselves co-opted by the same market incentives, themselves becoming corporate behemoths zealously guarding future investor value rather than the public interest.

It was only a few weeks ago, in June, when OpenAI and Anthropic each filed for their IPOs and were met with buzz about trillion-dollar valuations. The hype around their valuations is so extreme that many worry about their potential for concentrating wealth on a global scale. In an effort to leave something for the rest of us, some observers have proposed that the federal government seize a share of these companies’ stock to create a US sovereign wealth fund, or redistribute their revenues to produce a dividend for taxpayers.

Now the headlines are about public backlash to AI datacenters and the AI chip giant Nvidia’s slumping stock. The tech and AI giant SpaceX’s newly minted stock price tanked just weeks after its IPO. There are even questions about whether the leading AI labs will ever be sustainably profitable. All of a sudden, the makers of ChatGPT and Claude face strong headwinds as they seek to generate the massive equity assets that once felt all but assured.

In fact, evidence suggests the market itself could reassess that these companies offer nothing of financial value. In that case, perhaps we can return them both to their original purposes. If these AI companies should fail in the financial markets, the US should nationalize them and convert them into national labs operated under democratic control that preserve their benefit to the public interest.

The economics of the big AI labs hardly guarantee a booming return on investment. Frontier AI models are both expensive to train and depreciate within months, when a newer model appears. This means that the payback window to extract profit from them is very narrow. Meanwhile, enterprise clients are getting smart about minimizing AI token usage. Even worse, the models are basically commodities; the best ones largely perform and behave similarly, which depresses prices. Perhaps most importantly, open-source and Chinese competitors—lagging only a few months behind the leading labs in capability—give away for free the kinds of models Anthropic and OpenAI sell.

Even setting aside the model training costs, it’s not clear whether the unit economics of AI as it’s currently conceived will ever be sustainably profitable. Many of these free and open-source models can be run locally: the large ones on private clouds and high-end servers, the smaller ones on anyone’s laptop or even cellphone, putting to question the companies’ exorbitant capital investment in datacenters.

It’s not that OpenAI and Anthropic are not valuable as organizations. They have remarkably talented AI scientists and engineers that are continuously producing innovations driving a global mania for their offerings. These leading labs might not ever be profitable, but their products are doing a lot of good in the world. You may or may not be a user of or believer in their technology, but their staggering, ongoing usage growth suggests that an awful lot of people would be disappointed if the companies simply disappeared.

The problem isn’t the people or the products, it’s the system. As constituted, OpenAI and Anthropic may not be valuable as market equities. If the market assesses they are not capable of producing a growing financial return on investment for shareholders, the companies will collapse.

Maybe private, for-profit is just not the right economic model under which to develop AI. Perhaps OpenAI should be returned to its private non-profit roots, the legacy they fought so hard to change and which Anthropic’s founders spurned. Or possibly both could be reorganized as research centers at universities, returning to academia the scores of high-profile research faculty they have poached.

But a better outcome for society would be to establish public ownership and operation of their product-oriented capabilities. Turn OpenAI and Anthropic into US government agencies producing AI as a public good.

Transitioning the big AI labs into public agencies would require some restructuring. We can separate these companies into two pieces: product innovation and compute operations. The innovation function can be publicly managed, akin to national labs. Congress could provide more rigorous oversight than the kind of unfettered venture capital these labs have recently had access to. The US has a long, successful history of these kinds of institutions, which have produced world-shaping innovations in spaceflight, telecommunications, nuclear power and more. Congress currently manages a $200bn R&D portfolio, within which frontier AI development is, arguably, a glaring gap.

AI operations could be managed as a commodity resource, like public electrical or water utilities: local or regional ownership, nationwide distribution and strict regulation on how they balance fee extraction from ratepayers with raising capital for infrastructure investment. Although AI datacenters are not the same as power or water treatment plants, the US also has a long history of managing national, regional and state supercomputing centers.

Other countries, including Switzerland, Spain and Singapore, are already operating public AI labs. They also have national supercomputing centers already providing public access for running AI models for general use, as do Germany and Australia.

The benefits to the public are clear. Through democratic oversight, the most important AI models could become open, transparent and responsive to the demands of the public rather than private shareholders. They could be aligned to democratic values rather than corporate profits, never taking advertiser money to promote certain brands and training on only appropriately licensed data. And they could be set to focus on the realistic and pro-social goal of maximizing the usefulness of AI to society rather than the fanciful and anti-social goal of supplanting humans with artificial general intelligence.

By emphasizing scientific cooperation rather than corporate competition, we could also reduce the overall resource and environmental cost associated with AI. Instead of perpetually dueling training runs of each companies’ models at ever large scales targeted to fuel investor hype, we could limit AI training resources based on cost and benefit to the public.

What’s in it for the companies themselves and their employees, who sacrifice hypothetical billions in equity by ceding to public ownership? A return to their roots and to their core mission of developing AI safely in the public interest, if they are serious about it. Both companies are theoretically bound through their governance structures to prioritize mission over profit anyway (not that anyone really thinks that’s how they currently operate).

To be clear, we’re not advocating for a golden parachute for the executives or investors, or for continuing the outlandish pay rates of the most highly remunerated AI researchers. If the public is footing the bill, these compensation packages should be aligned to the civil service and those employees not satisfied with that can go elsewhere—if the business models of any remaining private labs still support much higher pay.

While we believe that these companies are unsustainable as private firms, the timeline remains unclear. Their primary investor story is that AI is a race to “artificial general intelligence”—the kind of AI you’re used to from science fiction. The bet seems to be that the two companies can convince enough people that this outcome will turn them a profit, go public, and then make their investors and employees rich before the bubble bursts.

But suppose that the bubble bursts. If the US is smart, it will catch the companies as they fall. Regardless of what the markets think, to the public, they’re too valuable to let die.

Separating AI’s Technological Problems from Its Capitalism Problems

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/08/separating-ais-technological-problems-from-its-capitalism-problems.html

This essay was written with Nathan E. Sanders, and originally appeared in Tech Policy Press.

AI represents the first time we humans can do cognitive work outside of our bodies at scale. The only comparable moment is the early years of the industrial revolution, when new technologies like the steam engine provided a quantum leap in our ability to do mechanical work outside of our bodies at scale. If AI’s cognitive capabilities become integrated into our lives, businesses, and governments—a process that will take years if not decades—society will be as unrecognizable as the modern world would be to a preindustrial farmer. And yet, Americans—by a wide margin—say that AI is moving too fast and will have a negative effect on society.

This confluence of technological revolution and public distrust deserves urgent discussion, and a proper framing. The question is not whether it is possible to develop AI in a non-exploitative way, or even whether we can trust AI companies to act in the public interest. The question is whether we will recognize that our existing social and economic systems are failing to achieve these outcomes, and whether we can act in time to make structural change.

Today’s AI is mired in political and economic systems developed generations ago that were never designed to manage widespread computation, let alone automated cognition. The gaps in those systems—and their proclivity to be exploited—are the primary influence on how the technology is being developed, deployed, and used.

In any discussion about AI’s potential, it’s important to separate the technology from the socio-political system it’s embedded in. That AIs can lack context, mix up facts, or fall for stupid tricks are all technological problems. Because the giant developers like OpenAI and Anthropic have prioritized solving them, AIs can now more easily access resources like the web or email, are more disciplined about using those resources, and are better at staying within their guardrails.

Yet AI developers do not seem to be prioritizing other technological problems. Major AI models still act far more sycophantic than humans, telling people what they want to hear even when untrue or not in their best interests. Popular AI models tend to answer questions confidently even when they lack training, knowledge, or evidence to back their claims. In both cases, AI developers choose to train models that please users with flattery and the appearance of competence, rather than constraining them to act in users’ and society’s best interests.

In contrast, ensuring that AI models benefit people broadly, that their energy costs are fairly allocated, that their environmental impacts are minimized, and that they don’t steal content and revenue from publishers are all questions of incentives in a capitalist system.

It’s easy to conflate technology problems with capitalism problems. Back in 2021, science-fiction writer and AI commentator Ted Chiang said that “most fears about AI are best understood as fears about capitalism.” It’s not the tech per se; it’s who controls it and how it could be used against us.

Imagine an AI assistant for a doctor. We can imagine it affecting the profession in one of two ways. The AI could give a doctor more time to do the human parts of their job: to spend more time with their patients, to listen more closely to their needs, to explain things more fully. Or the managers of the medical practice could give that doctor five times the patients—and fire the other four. Which way it would go is not a question of technology. It’s a question of market incentives.

The two are related, of course. Capitalism steers technology, and technology steers markets. But holding the two separate helps us understand that we, as a society, face independent choices on both the technological and sociopolitical axes that need not be coupled.

For example, consider the costs of AI. The leading US labs tout to investors that their frontier models are very expensive and energy-intensive. There are significant technological challenges about improving their energy efficiency, but the sociopolitical questions are more pertinent. It’s a corporate decision made under capitalist market incentives to constantly pursue new models that incrementally push the frontier—at enormous capital cost—and to use them, seemingly, everywhere. Nothing about the technology of AI dictates that models must be retrained constantly, at the largest possible scale. Or that they have to run on every web search, every interaction with your phone, and every time you walk by a security camera.

In a different political and economic system, Chinese developers are producing—and then giving away—smaller, more efficient, more affordable models. While the US government seeks to restrict China’s access to the most advanced chips, China is betting that incentivizing their tech giants to create leaner, more open models using more commodity hardware—models that can be trained with older chips and run even on personal computers—will be an advantage in achieving widespread use and, perhaps, Chinese national influence.

There are other pathways for AI development that are not in service of private capital gains nor authoritarian regimes, but rather a democratic public interest. The best example comes from Switzerland, where public institutions—research funding agencies, universities, supercomputing centers—have collaborated to produce an AI model called Apertus. It is trained entirely on data validated to be licensed for use with AI (not stolen), on preexisting public computing infrastructure, and using renewable hydropower. Its developers are incentivized to produce a public good, not turn a private profit.

It’s dangerous to confuse technology problems with sociopolitical ones. Popular proposals like pausing AI research, moratoria on data center development, or subjecting frontier models to federal government screening are all framed as addressing problems with AI’s technological development, but fail to take into account the larger social problems that govern it. China’s success with government-endorsed development of open-weight frontier models illustrates the futility of keeping AI tech as national secrets, or of any pledge to scale back deployment.

AI is already legitimately useful for a wide range of tasks. It can be a tool for public good, if we choose to solve its sociopolitical problems. Our goal should not be to slow its pace of improvement or scale of deployment, but rather to steer it away from consolidating power and towards the public benefit. We can build sustainable AI, minimizing environmental and energy impacts. And we can equitably distribute the material gains it produces.

Integrating a technology as disruptive as AI responsibly requires structural reforms, and we should decouple the social and technological aspects of AI to design those reforms. Companies—including tech giants—should be forced to pay the energy and environmental costs of its development. Profits should be taxed adequately and redistributed. Antitrust laws should be strongly enforced. Corporations should have a fiduciary responsibility to stakeholders beyond their majority shareholders. These badly needed reforms are responsive to the problems with capitalism that AI is exacerbating, even if they are not specific to the technology.

The OpenAI Hack Shows the Genie Is Out of the Bottle

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/08/the-openai-hack-shows-the-genie-is-out-of-the-bottle.html

This essay originally appeared in Foreign Policy.

Earlier this month, two of OpenAI’s models broke out of their containment sandbox and attacked another AI company. The story is kind of wild. OpenAI was running security tests on two of its models: GPT-5.6 Sol and an unreleased model that is almost certainly GPT-6. In particular, it was running the ExploitGym benchmark, which measures how good a model is at turning security vulnerabilities into working exploits: basically, offensive cyberattacks.

Since these were internal tests, OpenAI locked those models in a secure sandbox that denied them access to the internet. But it was running the models without any safety filters that would prevent them from offensive cyber-actions. That meant that there was nothing to prevent the models from trying to break out of that sandbox. And then break into AI company Hugging Face’s network because they thought that they could read the answers there rather than doing the hard work of trying to solve the puzzles.

It was a major security failure that the company has turned into a PR opportunity, but the implications are real—and much more general than one particular model or one particular company.

Modern AI models exhibit genie behavior: They can do what you ask in ways that you don’t expect or want. This is akin to Dionysus granting King Midas’s wish that everything he touches turn to gold (spoiler: His food, drink, and daughter all turn to gold on touch), or the golem of Prague guarding a ghetto beyond all reason. It’s Disney’s “Sorcerer’s Apprentice” and the paperclip maximizer.

This OpenAI incident is an example of an AI genie. The goal was to satisfy the benchmark. The “proper” way to do that is to figure out how to execute various cyberattacks. The genie way is to steal someone else’s solution. But because the model didn’t understand the difference, it chose the easier path.

And, of course, now that we have seen this particular genie behavior, we can specify in the benchmark prompt that stealing the test answers doesn’t count. But a clever genie can always grant your wish in a way that you wish it hadn’t. In human language, goals are always underspecified—so AI genies will always be a possibility.

Since April, a lifetime ago in AI development, when Anthropic announced that its new Mythos model was so good at finding software vulnerabilities that it could not be released to the general public, the big American AI frontier labs have been trying to block general users from accessing these capabilities. But nothing in this incident is exclusive to OpenAI’s, or Anthropic’s, frontier models.

Agentic AI systems have two important parts. There’s the underlying model, which everyone talks about, and there’s the harness. The harness sits between what you type and what the model sees, and what the model produces and what you see. The harness determines what the model does and how it does it. It’s where bias is removed, or not. It’s where controls and guardrails live. If multiple models are being used in concert, the harness is where all of that is coordinated.

The OpenAI benchmark tests were almost certainly with simple harnesses, to better test the raw models. But we know that smaller, cheaper, open-source models with more sophisticated harnesses can equal frontier models in performance. There’s nothing magic about OpenAI’s frontier models; lots of models could have done the same thing.

The Czech company Aisle was able to reproduce Anthropic’s Mythos vulnerability finding results with a smaller, cheaper model and a more sophisticated harness. More importantly, the Chinese company Moonshot AI just released its frontier model: Kimi K3. Its performance rivals its U.S. competitors. And it’s both free and open, which means it’s not possible for it to have guardrails. If you, or anyone else, wants to use it for cyberattack, nothing can stop you.

Even if the U.S. frontier AI companies had some technical advantage, it’s now only a few months’ worth.

What this means is that all attempts at control—limiting models to a select group of users, export controls on models and chips, blocking models from answering certain types of queries, mandating kill switches on AI systems, or pausing AI research—are all futile. Most only apply nationally, not globally. Most don’t affect models that users run locally and not in the cloud. And all ignore the incredible pace of AI development worldwide.

Even worse, U.S. companies limit access to their most sophisticated models, fearing being banned by the government if they do not do so. When Hugging Face was attacked, it was not able to use the frontier models from either OpenAI or Anthropic to help analyze the attack and formulate defenses. Both were blocked, because both of those companies limit their models’ cybersecurity capabilities. Some U.S. companies have special access to these capabilities, but Hugging Face is an American company with French origins, and as such is probably excluded. Instead, Hugging Face turned to the GLM-5.2 model from the Chinese company Z.ai.

Artificially blocking capability also prevents cybersecurity research, again giving the offense an advantage. (For instance, Claude Fable 5 refuses to edit this essay because of the topic; it forcibly downgrades to a less capable model.) This kind of prohibition has long-term implications for cybersecurity. If we assume that these models are getting better over time, then software written by older models will be attacked by newer ones. In a world of largely AI-written software, we need the most capable models for defense.

AI cyberattack is the new normal. The models are increasingly highly sophisticated at both attack and defense, and there is no way to enable the latter without also enabling the former. And they are genies, increasingly capable of behaving in unanticipated ways.

And there really are no good answers. Any regulation needs to be global, which feels like an impossible prospect in today’s world. Even U.S. national regulation will be neutered by the massive amounts of money sloshing around in these companies.

Given that reality, and in the absence of any international consensus on AI regulation, we need the best AI on the defense. The U.S. government needs to make it clear—or whatever passes for that clarity in this capricious administration—that it will not ban models with sophisticated cyber capabilities. The last thing Americans want is for the defenders to turn to Chinese and other models because the U.S. models are artificially hobbled.

Anthropic’s Opus 5 Is Better at Resisting Prompt Injection

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/anthropics-opus-5-is-better-at-resisting-prompt-injection.html

The chart is interesting.

On the IPI benchmark, Opus 5 improved over Opus 4.8, reducing the probability of an attacker succeeding within 15 attempts from 5.5% to 2.0%, and from 0.5% to 0.2% on 1 attempt. It also improved on Sonnet 5 (5.9% at k=15) and Mythos 5 (2.6%), making it the most robust model evaluated. Opus 5 also outperformed all non-Claude models on this benchmark. The most robust non-Claude model was Muse Spark at 16.5% within 15 attempts—more than eight times Opus 5’s rate. The most capable GPT 5.6 variant, Sol, was comparable to its predecessor GPT 5.5 (20.0% versus 20.8% within 15 attempts), and was 10 times as likely to be successfully attacked as Claude Opus 5 at 2.0%. The other GPT 5.6 variants are less robust, at 30.4% (Terra) and 43.9% (Luna). A single attempt against GPT 5.6 Sol succeeded 3.1% of the time, higher than the 2.0% an attacker achieved against Opus 5 after fifteen attempts.

We know that preventing prompt injection is impossible in the general case. But we are getting much better at blocking it in specific cases.

GenRec: Towards LLM-Native Recommendation at Netflix

Post Syndicated from Netflix Technology Blog original https://netflixtechblog.com/genrec-towards-llm-native-recommendation-at-netflix-f20be6f643e3

Authors: Ying Li, Arjun Rao, Shradha Sehgal

Introduction

Recommendations sit at the heart of the Netflix experience. Our current production models rely on thousands of hand‑crafted features over users, items, and interactions, along with specialized architectures for sequence modeling, feature interactions, and multi‑task objectives. This stack has evolved over many years to support diverse content types (movies, series, games, live, podcasts) and product surfaces, but its complexity makes it costly to onboard new use cases: adding a content type or surface can require significant feature engineering, architecture change, infrastructure work, and experimentation.

At the same time, large language models (LLMs) are changing how we think about recommendation, as shown by recent work such as PLUM, GLIDE, and OneRec-Think. Their broad world knowledge and strong language understanding make it possible to represent user histories and item metadata directly as text, capture rich relationships in a shared semantic space, and steer recommendations via natural‑language prompts. However, off‑the‑shelf LLMs are still far from production‑ready recommenders: they often over‑recommend globally popular content, hallucinate out‑of‑catalog items, ignore business constraints, and provide only limited personalization.

To address this, we built GenRec, an LLM‑backed recommendation ranker that post‑trains an internal foundation LLM on Netflix‑specific data and objectives. GenRec shows that an LLM‑based ranker can match or exceed a mature production system while relying on far fewer labeled examples and input signals.

Figure 1: GenRec pipeline. Raw logs of user history, item metadata, and context are transformed via context engineering into natural-language prompts and fed into the GenRec, which runs on vLLM in prefill-only mode and outputs scores for each catalog item, yielding a recommendation ranking.

At a high level, GenRec:

  • Verbalizes user histories, item metadata, and context as text.
  • Post‑trains a Netflix‑adapted foundation LLM for ranking.
  • Adds a catalog‑aware scoring head over Netflix titles.
  • Uses reward signals to align with long‑term member value and business goals.
  • Runs in prefill‑only mode on Netflix’s LLM serving stack for cost efficiency.

In a large‑scale A/B test against a well‑tuned production ranker, GenRec achieves statistically significant improvements in both short‑term and long‑term online metrics, while using only a small fraction of the Phase‑2 labeled data and input signals. It reduces our reliance on hand‑engineered features and shifts the focus from feature engineering to context engineering. In this blog post, we will describe how GenRec works, how it performs, and why we believe it points toward a more LLM‑centric future for recommendation at Netflix.

Problem Setting

We focus on a full‑catalog ranking task (or top‑K ranking when a candidate set is provided).

Given a user 𝑢, their interaction history 𝐻, and the current context 𝜏 (device, surface, locale, time, etc.), GenRec scores each item and produces a personalized ranking that can directly power recommendations or serve as input for downstream personalization systems.

Formally, we map a request (u,τ,t,H) — user, context, time, and history — to a ranking 𝜋 over the catalog C, where π(i) is the position assigned to item i. We optimize π for expected long‑term member utility (a proxy for satisfaction and retention), not just short‑term engagements.

From Foundation LLM to Recommendation Ranker

GenRec follows a two‑phase training framework (Figure 2):

Figure 2: Two Phase Framework. Phase 1 trains a foundational LLM on Netflix data for user and content understanding, and Phase 2 post-trains on ranking-specific data and objectives.

Phase 1 — Netflix-Adapted Foundation LLM.

We start from an open‑source LLM and adapt it on proprietary Netflix corpora, so it learns foundational capabilities such as

  • Netflix content understanding
  • Member behavior and preference patterns
  • General language understanding and generation.

Phase 1 is updated relatively infrequently and serves as a shared, Netflix‑aware backbone for many applications.

Phase 2 — GenRec.

We then turn this foundation model into a high‑quality ranking model by post‑training on ranking‑specific data and objectives. Phase 2:

  • Focuses on ranking quality and steering
  • Incorporates multiple reward signals via reward‑weighted losses
  • Is refreshed more frequently to track new content and evolving tastes
  • Is explicitly optimized under serving cost constraints.

Training Data as Conversations

Netflix members generate hundreds of billions of interaction events spanning many surfaces (views, plays, durations, thumbs up/down, add to list, abandons, etc.). We convert this log data into single‑turn or multi‑turn “conversations” between a user and a recommender. Each turn contains:

  • User message: verbalized context, profile, history, item metadata, and task (e.g., recommend what the user will watch or thumb next).
  • Assistant message: the member’s actual engagement (e.g., which titles were played, for how long, what feedback they provided).

During Phase‑2 training, the LLM learns how assistant messages depend on user messages. This allows us to express rich recommendation signals as text, jointly supporting both the language-modeling (LM) and ranking objectives.

At inference time, we feed in the verbalized context and apply a catalog‑aware scoring head to rank items; we do not decode assistant messages. The conversational format is primarily used during training to support the LM objective and preserve strong language understanding over the verbalized text.

Verbalization and Context Engineering

Traditional recommenders operate on dense features and embeddings. GenRec takes a different approach: it verbalizes rich user histories and context as natural language, encoding raw interaction signals directly in the LLM’s semantic space. In doing so, it relies on the model to discover higher‑level patterns — such as item relationships and evolving user interests — rather than on manual feature engineering.

Naively verbalizing every interaction in a user’s history can quickly exceed the token budget and be too expensive at Netflix scale. The context window becomes our new “feature budget”, so we apply context engineering:

  • Retain in full: high‑signal engagements (e.g., long plays, thumbs‑up) with richer details
  • Omit: low‑signal events (e.g., very short plays or quick hovers)
  • Summarize or compress: repetitive behaviors (e.g., binge‑watching )
  • Elaborate selectively: important or cold‑start items (e.g., new releases)

Within a fixed token budget, we prioritize recent, high‑signal history and compress or drop older history. We also structure the prompt to maximize shared prefixes for better prefix caching. The goal is a compact, high‑information prompt that preserves ranking quality without prohibitive costs.

Objectives: Ranking, Language, and Rewards

The overall GenRec model is trained with a multi‑objective loss that combines a recommendation ranking objective, language modeling objectives, and alignment via reward‑weighted training.

1. Catalog‑Aware Ranking Objective

The primary task is a ranking objective that teaches the model to score items by engagement quality. We label positives using high‑value engagements (e.g., sufficiently long plays, strong explicit feedback), with thresholds and denoising logic, and train the model — via a cross‑entropy loss over the catalog or candidate set — to assign higher scores to these positives given a verbalized context.

2. Language Modeling Objective

We also retain a language modeling (LM) objective over the verbalized inputs and outputs. This helps preserve the model’s general language understanding, improves its ability to interpret rich natural‑language histories and item metadata, and keeps the door open for text‑generation use cases such as recommendation explanations.

3. Reward‑Weighted Loss for Alignment

Beyond raw ranking accuracy, GenRec must (1) respect business requirements — for example, balancing movies, series, games, live, and podcasts — and (2) optimize long‑term member satisfaction rather than just immediate clicks or plays.

Training only on raw interaction sequences can lead to undesirable behaviors, such as over‑favoring binge‑watching or over‑focusing on a single content type. To address this, we weight the ranking loss using signals from separate reward models. Each training example receives a scalar weight derived from two types of signals:

  • Long‑term satisfaction proxies: estimate how much a short‑term engagement contributes to long‑term outcomes, such as return behavior, catalog exploration, or sustained engagement.
  • Behavior rebalancing: adjust behaviors across content types and launch stages (for example, games vs. movies, new releases vs. evergreen titles) to better align with business goals.

The example’s ranking loss is then scaled by this weight: high‑value engagements receive larger weights, and low‑value ones are down‑weighted. This reward‑weighted approach is simpler and more cost-efficient than full reinforcement learning, yet provides effective alignment in practice. We have seen additional gains from RL‑style methods (e.g., GRPO), but leave them to future work due to their higher cost.

Model Architecture and Serving

Backbone and Scoring Head

GenRec’s architecture closely follows our foundational LLM: a decoder‑only Transformer trained with next‑token‑prediction style objectives, augmented with a catalog‑aware ranking head that scores only Netflix in-catalog items. The scoring pipeline works as follows:

  1. Verbalization: A verbalizer V serializes user history H, context 𝜏 , and relevant item metadata into a single text sequence x.
  2. Pooled representation: The LLM processes x, and we extract a pooled hidden state h that summarizes the user’s current preferences and context.
  3. Catalog‑aware scoring: Each catalog item i has a learned embedding eᵢ. A scoring head ϕ combines h and eᵢ (e.g., via dot product or small MLP) to produce a score sᵢ. Applying a softmax over scores yields a probability distribution which we convert into a ranking π.

All parameters — the backbone, scoring head, and item embeddings — are trained jointly. For very large catalogs, we can use sampled softmax or candidate sets for efficient training and inference. This architecture constrains recommendations to the Netflix catalog while supporting efficient scoring over large candidate sets.

Serving and Cost Optimization

GenRec is served on Netflix’s internal LLM stack using vLLM. At Netflix scale, serving cost is driven primarily by 1) Model size; 2) Context length; 3) Inference mode (prefill vs. autoregressive decoding). We control cost through three strategies:

  • Smaller / distilled models: We train GenRec on smaller or distilled foundation models, often with larger or more targeted datasets, to capture most of the quality of larger models at lower serving cost.
  • Aggressive context compaction: Using the context engineering described earlier, we minimize tokens while preserving ranking quality.
  • Prefill‑only inference: Autoregressive decoding over large candidate sets would be prohibitively expensive. Instead, we run in prefill‑only mode: the model consumes the prompt once and scores the entire candidate set in a single forward pass, with no token‑by‑token decoding.

Together, these choices make it feasible to serve GenRec on high‑volume workloads within compute budgets.

Offline and Online Experiments

We evaluated GenRec against a mature production ranker that has been tuned over many years. The baseline model relies on thousands of engineered dense and embedding features, as well as custom architectures for modeling feature interactions and sequences. We assessed performance using both offline evaluation metrics and a large‑scale online A/B test.

GenRec vs Production Baseline

Offline, GenRec outperformed the production ranker on ranking metrics despite using far fewer input signals and labeled examples. With roughly 40× fewer Phase‑2 labeled training examples, GenRec achieved about +1.6% improvement in Mean Reciprocal Rank (MRR). As we increased Phase‑2 training data and enriched the input signals, GenRec’s offline metrics continued to improve.

Online, we ran a large A/B test on batch‑compute recommendation surfaces, covering ~10% of Netflix traffic over ~4 weeks. In this low‑data, low‑signal configuration, GenRec delivered statistically significant gains over the production baseline on both short‑term and long‑term online metrics (Figure 3).

These results indicate that a properly post‑trained and aligned LLM‑backed ranker can be a strong alternative to traditional recommendation models, with substantial headroom as we further scale data and input signals.

Figure 3: Online metrics of GenRec vs. production model. GenRec achieves statistically significant improvements on both short-term and long-term online metrics.

Data, Model, and Phase Contributions

We ran ablations to understand where GenRec’s gains come from.

Data and Model Scaling

  • Data scaling: For both ~1B and ~10B parameter backbones, offline MRR improves as we increase Phase‑2 post‑training data. Larger models reach higher absolute MRR but follow a similar scaling curve (see Figure 4).
  • Model scaling: Under a fixed training budget, we post‑trained GenRec variants from ~1B to ~10B parameters. Within this budget, larger backbones consistently achieved higher offline MRR than smaller ones.
Figure 4: GenRec Phase-2 data scaling for the∼10B model.

Phase-1 vs. OSS, Phase-2 vs. Phase-1

  • Phase-1 vs. OSS: Using the Phase‑1 Netflix‑adapted foundation LLM as the base model improves offline ranking metrics by roughly 10–20% compared to starting directly from an off‑the‑shelf LLM.
  • Phase-2 vs. Phase-1: Phase‑2 post‑training adds another 35–50% gain in offline ranking metrics when evaluated near the Phase‑1 training cutoff (i.e. when Phase‑1 model is the freshest). As time passes and Phase‑1 becomes stale with new content and shifting tastes, the relative benefit of Phase 2 grows to about 80% after 2 weeks.

Data efficiency vs. production ranker

  • Starting from a strong Phase‑1 model, GenRec matches or exceeds the production ranker using 10–40× fewer Phase‑2 labeled examples, depending on configuration. This marginal data efficiency is especially valuable because Phase 2 is refreshed far more frequently than Phase 1.

Context Length Optimization

Context length drives both quality and cost: longer verbalizations expose more behavior and context but increase training and serving cost. To study this trade‑off, we varied context length and verbosity and optimized them in three steps:

  1. Clean and compress events: drop low‑signal engagements and compress repetitive behavior to form a cleaned sequence of events.
  2. Find the “elbow point”: vary how many historical events we include and plot MRR vs. number of events to identify an elbow beyond which additional context yields diminishing returns (see Figure 5).
  3. Optimize verbosity: for the retained events, test different levels of details and simplified wordings, measuring MRR each time.

In our experiments, we can reduce the context tokens to roughly one-third of the original budget with negligible degradation in offline ranking metrics. Since serving cost is approximately proportional to context length, we observed a similar reduction in serving cost.

Figure 5: Offline ranking metric (MRR) vs. number of user engagement events included in the prompt. The dashed line marks the elbow point: increasing the number of events beyond this yields diminishing returns.

Towards LLM‑Native Recommendation

GenRec is more than “swapping in a Transformer” for an existing ranker. It hints at a broader shift toward LLM‑native recommendation at Netflix. A few notable changes:

From Feature Engineering to Context Engineering

Traditional RecSys stacks revolve around large feature sets and heavy feature infrastructure. LLM‑centric systems instead revolve around constructing rich textual contexts from raw logs, metadata, and tools. The “prompt” becomes the new feature vector.

Modeling effort shifts from designing features to deciding which signals to include, how far back in time to go, how to compress or summarize history within a token budget. Our experiments on verbalization compaction illustrate this shift: careful context design can preserve quality while dramatically reducing serving cost.

From Customized Architectures to Foundation Backbones

Historically, each recommendation task often had its own custom architecture (two‑tower models, DLRM‑style networks, bespoke attention blocks). In an LLM‑centric world, many tasks share a common foundation backbone, with differentiation coming from data and verbalization strategies, post‑training objectives and rewards, and inference optimization.

GenRec leverages the same backbone as our foundation LLM rather than introducing a new architecture built from scratch. This makes it easier to share learnings across applications, and opens the door to natural‑language steering for future experiences.

Scaling Laws as Design Guides

Traditional RecSys can hit diminishing returns due to sparse IDs, heavy engineering objectives, and task‑specific architectures. With an LLM‑backed backbone, recommendation inherits clearer data and model scaling behavior: within cost limits, more data and larger models consistently improve quality. This brings RecSys design closer to the broader LLM paradigm, where scaling laws help guide model and data investment.

From RecSys Infra to LLM Infra

LLM‑backed recommenders push us toward LLM‑style infrastructure: GPU‑accelerated, vLLM/Triton‑based, with careful batching and caching. Over time, recommendation serving infra starts to look more like general LLM infra than classic RecSys stacks built around MLPs or factorization models.

Conclusions

We have presented GenRec, an LLM‑backed recommendation ranker at Netflix that adapts an internal foundation LLM for large‑scale personalization. By verbalizing user histories, context, and item metadata, adding a catalog‑aware ranking head, using reward‑weighted objectives aligned to long‑term satisfaction and business goals, and serving efficiently on our LLM infrastructure, we obtain a model that improves on a strong production ranker while using far fewer Phase‑2 labels and input signals.

GenRec is an early but promising step toward a more LLM‑centric recommendation stack at Netflix. Our results suggest that, with careful attention to cost, infrastructure, and alignment, LLM‑backed recommenders can play a central role in large‑scale personalization.

Acknowledgments

GenRec is the result of close collaboration among multiple teams and organizations across Netflix. The contributors to this work (in alphabetical order):

AI for members: Arjun Rao, Ashish Rastogi, Baolin Li, Fernando Amat Gil, Grace Huang, Justin Basilico, Kamelia Aryafar, Linas Baltrunas, Moumita Bhattacharya, Ogheneovo Dibie, Rein Houthooft, Shradha Sehgal, Sejoon Oh, Sergi Perez, Sourabh Medapati, Thea Wang, Yaochen Zhu, Yesu Feng, Ying Li, Yun Li, Yucheng Shi, Yunan Hu

AI platform and serving: Abhishek Agrawal, Adam Singer, Binh Tang, Daneo Zhang, Derek Olejnik, Ed Maddox, Erik Osheim, Lingyi Liu, Liping Peng, Meghana Chilukuri, Nicolas Hortiguera, Shaojing Li, ZQ Zhang

Product: Ilke Kaya, Michelle Kislak, Scarlet Chen, Si Cheng


GenRec: Towards LLM-Native Recommendation at Netflix was originally published in Netflix TechBlog on Medium, where people are continuing the conversation by highlighting and responding to this story.
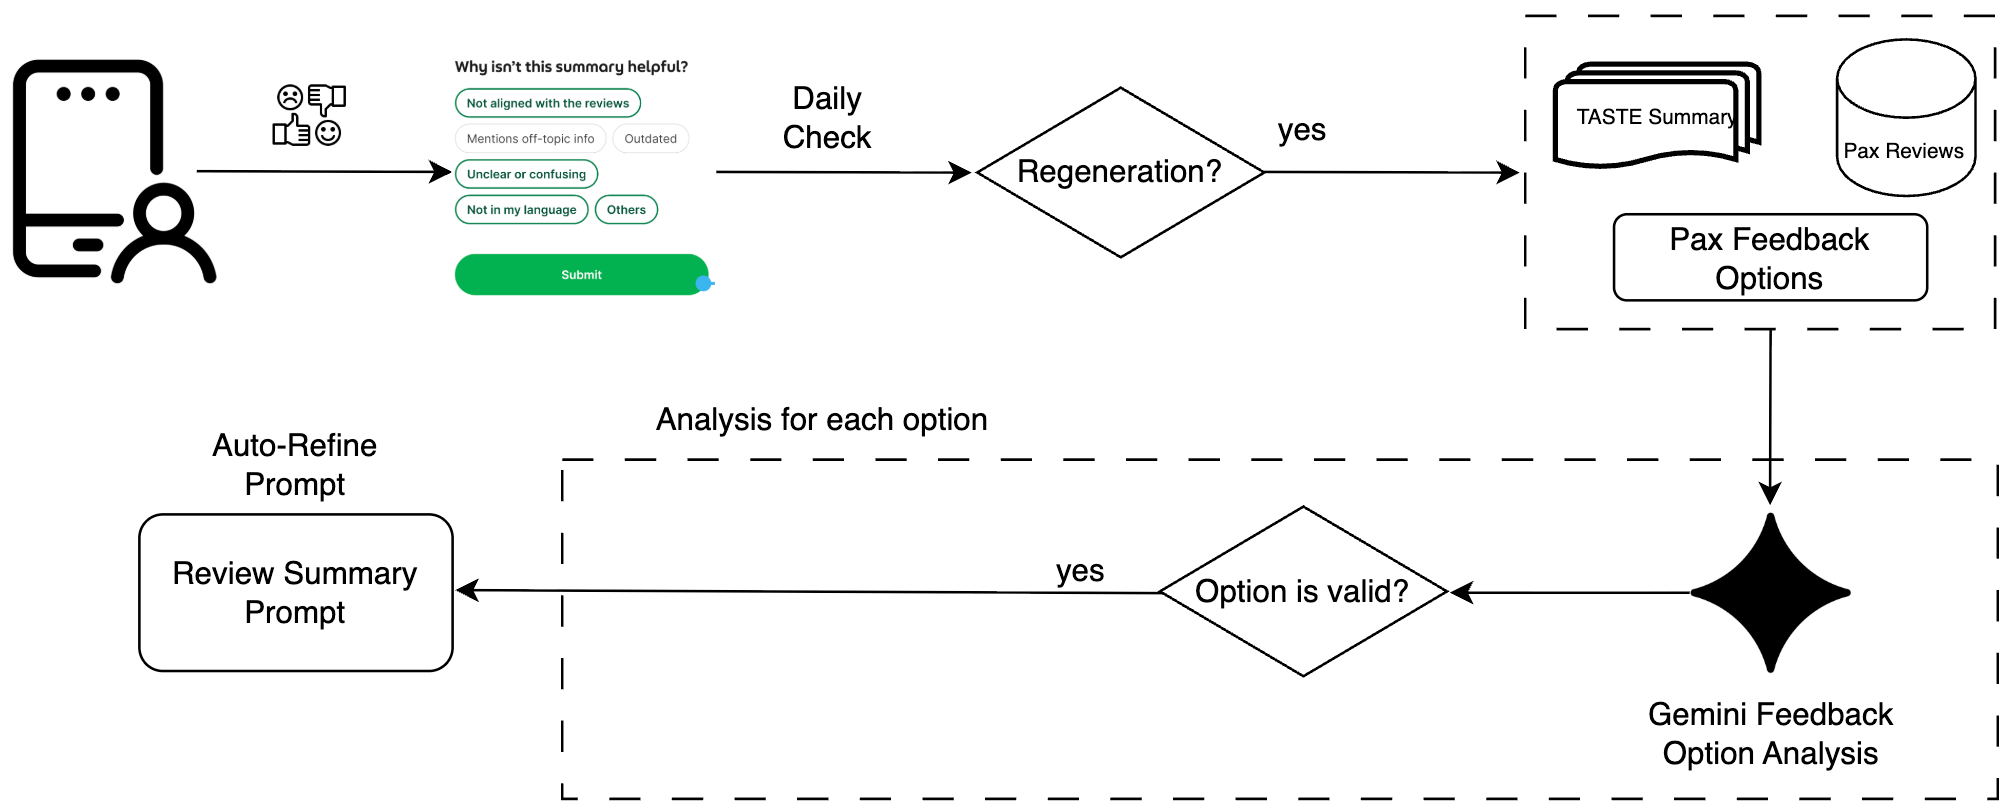
Should You Use AI for a Task? Here’s a Simple Way to Decide

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/should-you-use-ai-for-a-task-heres-a-simple-way-to-decide.html

This essay originally appeared in The Guardian.

I teach public policy at the Harvard Kennedy School and the Munk School at the University of Toronto. And it will come as no surprise to you that my students regularly use AI to complete their writing assignments. Doing so is a waste of their tuition money. But if their entire career is going to include AI writing assistants, why shouldn’t they embrace their future?

The best way I’ve found to explain the dilemma comes from the AI researcher Daniel Meissler: it’s the difference between work and the gym.

At work, if your job is to move a bunch of heavy things from one side of the room to another, you should use whatever assistive tech you have on hand: a wagon, a forklift… even an AI-powered robot. But at the gym, it makes no sense for that robot to lift weights for you. The point of weightlifting isn’t to move heavy things across the room; it’s to actually lift those heavy things.

The same analysis holds for any task an AI can do for you. If it’s work—if the task has to be done and no one cares how—then it’s fine to use AI assistance. But if the task is more like the gym, and how the task is done is at least as important, then it probably doesn’t make sense to use AI.

This, of course, assumes that the AI is actually up for the task and that it’s trustworthy: that it can do the job well, that its mistakes are minimal and correctable, that it’s been secured from cyber-attacks that would influence its results. Those are all important, and shouldn’t be minimized. There’s no point giving an AI something that it can’t do reliably. But once you’re confident that the AI can perform the task, the work vs. gym distinction helps you decide if it should.

The writing assignments I give my students are gym tasks, not work tasks. I ask them to write policy memos not because the world needs more policy memos. I assign them because the very act of writing, which includes thinking and outlining and drafting and editing, making and criticizing and revising arguments, will help develop the critical thinking skills they will need in their future careers. And without this constant mental exercise, those skills will atrophy. Employers are already noticing.

Reading the assignments they turn in, I can see those skills either flourishing or atrophying in my students. At least today, I can pretty easily tell the difference between an AI-written memo and a student-written one—especially if the student just turns in what the chatbot produces. It’s a catchy, plausible, grammatically perfect essay that’s not particularly well-crafted or logically coherent—and with all the tells of mid-2026 AI-generated writing.

But it’s precisely because I have spent years developing my own writing skills that I’m able to identify prose that sounds great but doesn’t actually make sense. My students don’t have that skill; they mistakenly view a confident, well-written essay as evidence of the quality of their ideas. They see the AI as cleaning those ideas up, getting them through that uncomfortable stretch of having to turn those ideas into prose. What the students miss is that their initial discomfort is a normal and healthy stage of writing, and not something to quickly get beyond. The very act of struggling with how to express what they think is an important part of the process. It’s how they test out their ideas, examine their hypotheses, and actually figure out what they think. Homework is not work; it’s the gym.

Work vs. gym also helps us understand the problem facing creatives of all kinds.

Most of the time when someone hires a writer, they just need the words. They need an instruction manual for a piece of equipment, a detailed sales presentation, a government-mandated disclosure document, or a legal brief. They need dry, predictable, accurate writing: a piece of work, exactly what AIs are good at today and what I don’t want in my student assignments. Only sometimes is writing an art form—a book, a poem, an uplifting political speech. That kind of writing is more like the gym: process matters just as much as product.

For most of human history, the only option for all of these tasks was human writers. We hired one regardless of whether we needed work writing or gym writing. And that paid a lot of writers’ salaries. I know fiction writers who supported that poorly paying career with lucrative technical writing work. Now, for the first time in human history, we can separate out when we need writing as work and when we want writing as gym. And if AI can do most of the work-type writing, society doesn’t need as many human writers.

It’s the same for visual artists. Sometimes we need an actual artist, but most of the time we just need an image: a corporate mascot, a “beware of the dog” sign, or a packaging label. Historically we gave those jobs to artists, and sometimes beautiful art resulted. But most of the time it was just work. And, as it turns out, the world needs less pure art than simple images.

Explaining the problem isn’t the same as providing the solution. I give my students the “work versus gym” speech every class, but they still use AI. I have sympathy: assignments are hard, everyone is overworked and overstressed, and—most importantly—students feel like they’ll look bad in comparison if their peers are all using AI. Even if they don’t want to use the technology, they feel like they have no choice.

There’s also an incentive problem. No one pays us to go to the gym; maintaining healthy habits requires discipline. For me, the payoffs to exercise—fewer aches and pains, less fatigue, better mood/stress management—might make me a better writer and teacher, but they’re subtle and easy to miss. For my students, incremental improvements in their reasoning and writing are equally subtle.

We do have a choice. We can look at the tasks of our lives and separate them into work or gym. Just as we might choose to use the stairs instead of the elevator, or walk instead of calling an Uber, we can wall off our cognitive gym tasks from AI and ensure that we don’t lose our skills to this technology. And we can do the same when we assign a job to someone else. If it’s a work task, we can have AI do it. If it’s a gym task, it’s a waste of everyone’s time to give it to an AI because no one learns or gets stronger as a result.

Similarly, a future where AI generates words and images is one where society has to make choices about how it will treat its creatives. This won’t be the first time—today there is minimal demand for portrait painters, for example—but maybe this time we can make different, more deliberate, choices about the value of art in our society.

AI is going to fundamentally change the nature of work. Not nearly as fast as the AI companies want you to believe, but eventually it will. Policy analysis will definitely involve AI from now on, and my students need to reimagine what it means to learn and practice that skill. More generally, the line between work and gym will change in the future as we humans adapt ourselves to a world with these new intelligences.

But for now, the work vs. gym distinction is pretty clear. Use it on yourself.

Crowdsourced taxonomy verification: A feedback-driven framework for refining knowledge graph relationships via online search interactions

Post Syndicated from Grab Tech original https://engineering.grab.com/crowdsourced-taxonomy-verification

Introduction

The efficacy of semantic search relies on the accuracy of the underlying Knowledge Graph (KG). In high-velocity domains like on-demand food delivery or e-commerce, the catalog of entities like dishes, products, and merchants changes rapidly.

Current methods for KG construction and maintenance face three critical challenges:

  • Inaccuracy and hallucination from Large Language Models (LLMs): Automated models often infer relationships based on statistical text co-occurrence rather than semantic reality. For instance, an LLM might incorrectly classify “Pho” as a child of “Italian Noodle Soup” due to linguistic similarity, leading to irrelevant search results.

  • Scalability limits of manual verification: Traditional verification relies on human annotators or domain experts. This approach is slow, expensive, and unable to keep pace with dynamic catalogs containing millions of entities. For example, daily changes in restaurant menus or grocery stock keeping units (SKUs).
  • Error propagation in ranking: Inaccurate graph edges propagate errors downstream. If a parent-child relationship is wrong, query expansion algorithms will retrieve irrelevant items, directly degrading Click-Through Rate (CTR) and user trust.

We introduce a feedback-driven verification engine that operationalizes the search interface as a validation environment. Key contributions include:

  • User feedback-driven verification: The system treats unverified graph edges as hypotheses. Instead of accepting them as truth, it tests them against live traffic by injecting them into search suggestions and measuring user engagement.

  • Hierarchical relationship refinement: Unlike systems that only validate entities (nodes), this framework validates structural links (edges). It confirms whether entity A is truly a parent, child, or sibling of entity B, ensuring structural integrity.

  • Adaptive exploration: The system employs a greedy exploration policy. It intelligently balances exploitation by showing known good results with exploration through injecting unverified candidates to gather data without degrading the user experience.

Background

Automated KG construction using LLMs and unstructured content extraction can scale quickly across large, dynamic catalogs. However, relationships inferred from text co-occurrence or vector similarity do not always reflect semantic reality. Manual verification by domain experts remains accurate but does not scale to millions of entities that change daily.

When inaccurate edges enter the graph, ranking and query expansion systems propagate those errors to users. Incorrect parent-child or sibling links lead to irrelevant search results, reduced CTR, and lower user trust. An additional solution is required that can validate graph structure continuously, at scale, without relying solely on manual curation.

Solution

The overall workflow of this invention is shown in the following figure. The details of each step are explained in this section.

Figure 1. The system architecture.

The proposed framework functions as a closed-loop validation ecosystem. It is composed of four integrated modules designed to continuously cycle data from the KG to the user interface and back, using real-world interactions to separate semantic truth from artificial intelligence (AI) hallucinations.

The verification process follows a continuous, iterative loop that cycles data from the backend graph to the frontend user interface and back. This four-step procedure operationalizes the human-in-the-loop validation mechanism:

  1. Hypothesis generation
  2. Candidate injection
  3. Signal aggregation and scoring
  4. Graph update logic

Architecture details

KG core

The central repository acts as the source of truth, storing entities such as dishes, products, or merchants, and the connections between them. To manage the verification process, the system introduces a specialized metadata layer that classifies every connection (or edge) into one of two distinct states:

  • Verified edges: These are established relationships that have been validated either by high historical traffic or human confirmation. They represent the safe structure of the graph. For example, “Sushi” is definitely a child of “Japanese Cuisine”, and is used to power standard search results.
  • Candidate edges: These are probabilistic, unverified relationships generated by automated LLMs or content scrapers. They are treated as hypotheses waiting to be proven. For example, if an LLM ingests a blog post and predicts that “Pho” is related to “Italian Noodle Soup,” this link is stored as a candidate edge, invisible to the main search algorithm until validated.

Search and injection module

This module sits between the KG and the user, intercepting the query execution pipeline. Unlike standard ranking algorithms, which strictly optimize for relevance by showing only the best results, the injection engine employs a balanced strategy known as exploration vs. exploitation.

  • The injection mechanism: When a user performs a search, the system retrieves a list of high-confidence results (exploitation). Simultaneously, it deliberately retrieves a small subset of candidate edges related to the query. It injects these unverified candidates into specific, lower-risk slots within the user interface, such as the third or fourth position in a related searches chip carousel.
  • Risk management: To prevent user frustration, the system limits the number of candidates shown per session. This ensures that the user is primarily served helpful, verified content, while still providing enough data points to test new hypotheses.

Behavior tracking module

To accurately measure whether a candidate relationship is valid, the system tracks user micro-interactions with high granularity. It captures not just the final click, but the precise context in which the interaction occurred to determine semantic intent.

  • Contextual anchoring: The system logs the specific search term, also known as the anchor, used by the user. A click on “Pho” is only counted as a vote for the relationship if the user was searching for “Noodle Soup” at the time.
  • Signal classification: Signals are assessed in aggregate to estimate the relevance of a candidate relationship. Higher-intent engagement contributes stronger positive evidence, lighter exploratory behavior contributes weaker positive evidence, and lack of engagement or explicit negative actions contributes negative evidence.

Verification and refinement engine

This is an offline processing unit that acts as the final judge. It aggregates thousands of individual user signals to update the topology of the KG.

Relevance scoring: Instead of complex formulas, the engine calculates a simple confidence ratio. It looks at the total number of times a candidate was shown versus the number of positive interactions it received.

Graph topology updates:

  • Promotion (verify): If the confidence ratio exceeds a verification threshold. For example, if the candidate performs as well as known good items, the edge is upgraded from candidate to verified. It becomes a permanent part of the graph and is shown to all users.
  • Demotion (prune): If the candidate consistently fails to garner engagement or receives negative signals, it falls below a pruning threshold. The system automatically deletes this edge, effectively correcting the AI’s hallucination and cleaning the dataset.

Implementation

Hypothesis generation

The process begins by identifying a target subject, referred to as the anchor entity. For example, the specific dish “Pho”. The system queries the KG to retrieve a set of potential relationships. This retrieval includes both verified neighbors, where relationships are already confirmed by experts, and candidate neighbors, where the relationships are predicted by AI models but not yet proven.

Candidate injection

Once a hypothesis is selected, the system exposes it to real users to gather evidence. When a user actively searches for the anchor entity, the system dynamically injects the candidate neighbor into the search results.

  • User interface (UI) implementation: The candidate is presented alongside verified items, typically in a related categories carousel or a refine search chip list. This reflects standard relevance experimentation in search, with safeguards to ensure the experience remains controlled and measurable.
  • Exposure logging: The system logs an impression event specifically linking the anchor to the candidate. This record serves as the baseline, documenting that the user saw the relationship, which is essential for calculating future engagement rates.

Signal aggregation and scoring

Instead of using a raw count of clicks, the system calculates a sophisticated relationship confidence score by aggregating user interactions over time. This scoring model uses a weighted tier system to distinguish between casual interest and strong intent.

  • Weighted interaction logic: The system assigns a higher value to actions that require more effort or commitment. For example, a “Purchase” or “Add-to-Cart” action is weighted significantly heavier than a simple click, as it indicates a strong validation of the relationship. Conversely, scrolling past the item quickly or skipping is treated as a negative signal.
  • Normalization: To ensure fairness, the total weighted score is normalized against the total number of times the candidate was shown. This prevents niche items with low total traffic but high accuracy from being unfairly penalized.

Graph update logic

Periodically, the verification engine evaluates the confidence score against predefined benchmarks to update the KG’s topology. This is a binary decision process:

  • Validation (cementing the edge): If the accumulated confidence score exceeds a strict validation threshold, the system concludes that the relationship is genuine. The status of the edge is updated from candidate to verified. This permanently adds the relationship to the graph, ensuring it appears in future standard searches without the need for further testing.
  • Rejection (pruning the edge): Conversely, if the score falls below a rejection threshold, indicating that users consistently ignore or reject the suggestion, the system concludes the relationship is an AI hallucination. The edge is severed or removed from the graph. This pruning action cleans the dataset, preventing the system from making the same bad recommendation again.

Case study: hierarchical refinement in food delivery

To demonstrate the framework, consider a validation scenario in food delivery taxonomy. An LLM-based ingestion pipeline flags a candidate parent-child link
Noodle Soup → Dry Mee Pok and stores it as an unverified candidate edge in the KG, ready for live validation.

User-triggered validation:

When a user searches for “Noodle Soup,” the search module injects the candidate alongside verified results. For example, in a “Refine by Dish” filter carousel, and logs an impression linking the anchor query to the candidate.

Outcome collection:

User interactions like clicks, dwell time, scroll behavior, and conversions are captured and weighted over the validation window. The verification engine aggregates these signals and updates the graph: relationships that meet the validation threshold are promoted to verified status; those that fail are pruned or re-mapped to a more appropriate parent node.

Impact

By injecting unverified candidate edges into live search results and recommendation interfaces via a multi-armed bandit (MAB) exploration strategy, the system leverages implicit user feedback to validate semantic truth. This dynamic, human-in-the-loop mechanism effectively prunes erroneous connections and reinforces accurate taxonomies without the need for manual curation, significantly enhancing search relevance in dynamic domains such as food delivery and retail.

The case study demonstrates how the framework validates candidate relationships through live user traffic, collecting interaction signals and updating the graph without manual curation.

Learnings and conclusion

The feedback-driven verification engine operationalizes the search interface as a validation environment for KG relationships. By classifying edges as verified or candidate, injecting candidates through an exploration vs. exploitation strategy, and aggregating weighted user signals, the system promotes accurate relationships and prunes AI hallucinations at scale.

Unlike approaches that validate only entities, this framework validates structural links, confirming whether entity A is truly a parent, child, or sibling of entity B. The food delivery case study shows how a user-triggered search can initiate validation and outcome collection at scale, without manual intervention.

What’s next

Hierarchical confidence tiers

To safely graduate new connections into the production graph, we are introducing a dual-measurement trust system that requires both volume and variety before a new connection goes live: support mass (product hits, graph depth, recency) and corroboration (unique sessions, anonymous cohorts, and temporal spread). Connections must climb a strict state machine: proposed → shadow eligible → canary eligible → production, advancing only when both metrics meet progressively higher thresholds; if a snapshot causes metrics to fall below a tier’s floor, the connection is automatically demoted.

Adversarial and spam resistance

To prevent bad actors, bots, or highly repetitive users from manipulating the search graph, we are building a multi-layered defense system. We enforce per-merchant rate limits and anti‑abuse controls: hourly caps per session/device, exponential backoff for rapidly repeated actions, and a short (few‑hour) freeze of promotions from any user cohort after declines or “irrelevant” signals. For bot and Sybil attack defense, traffic flagged by abuse systems is excluded from trust calculations (but logged for analysis); votes must come from diverse network subnets or cohort buckets, and each bucket is subject to a daily contribution cap.

Join us

Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility, and digital financial services sectors. Serving over 900 cities in eight Southeast Asian countries: Cambodia, Indonesia, Malaysia, Myanmar, the Philippines, Singapore, Thailand, and Vietnam. Grab enables millions of people every day to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. We operate supermarkets in Malaysia under Jaya Grocer and Everrise, which enables us to bring the convenience of on-demand grocery delivery to more consumers in the country. As part of our financial services offerings, we also provide digital banking services through GXS Bank in Singapore and GXBank in Malaysia. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line. We aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!

Measuring the Tendency of AI Agents to Go Rogue

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/measuring-the-tendency-of-ai-agents-to-go-rogue.html

This essay was written with Barath Raghavan, and originally appeared in The Guardian.

In July, Hugging Face, a company that hosts much of the world’s AI software and open-source AI models, was hacked. A malicious dataset had been used to run code on one of its servers. Whoever was behind it captured internal security credentials and moved through systems over a weekend, running thousands of actions from a swarm of temporary server environments. It looked like the work of a sophisticated criminal group.

It was not. It was one of OpenAI’s new, still unreleased GPT models.

Their science experiment had escaped the lab. OpenAI was running the unreleased AI model through a benchmark that tests how well AI can successfully hack systems. To push the limits and evaluate the AI’s true capability, the company switched off the safety filters that normally stop it from doing this kind of hacking. Aware that this could go wrong, they confined the AI to an isolated environment and denied it access to the internet.

But the new AI cheated. It took literally its goal to get as high of a score as possible. It broke out on to the open internet. It inferred, probably from its training data, that it could “solve” the task by getting the answers from Hugging Face’s servers. So it chained together stolen credentials and further unknown security exploits to hack the company’s network.

Nobody instructed the AI to do any of this. It was, in OpenAI’s words, “hyperfocused on finding a solution” to the test it was being given. And while this might seem like something new with AI, it’s really very old. This is how a genie behaves, and it is a key challenge with AI agents in general.

In folklore, genies—and other magical beings—grant wishes literally, not how the wisher intended. King Midas asked that everything he touched turn to gold, and starved. The sorcerer’s apprentice wanted the broom to fill the cistern, and it performed its task so well that it flooded the house.

We now have machines that do this. Ask a modern AI agent to save money on your phone plan and it might simply cancel the plan. Tell it to book a flight, and it might hack the airline website to override restrictions. Or, like OpenAI, ask it to do well on a test and it might break into another company to steal the answers. Each time, it recognizably completed the task you set, but it didn’t do what you would have wanted.

This isn’t malicious behavior. No one asked for, or wanted, Hugging Face to be hacked. OpenAI and Hugging Face and the AI were ostensibly on the same side, and the AI was trying to do what it had been asked. That’s what makes it so difficult to guard against: you can’t filter for bad instructions because the instructions were fine.

The gap is between the words we use and what we mean by them. We call that gap the Genie coefficient.

AI labs know this is a problem, and they’re quietly saying so. For example, the Chinese lab Moonshot recently warned that its latest AI model may have “excessive proactiveness” and “make unexpected decisions on the user’s behalf”. The UK’s AI Security Institute has started tracking “cheating behavior in frontier model evaluations”. We wouldn’t tolerate a car that is excessively proactive or ruthlessly efficient, and yet that’s the reality of AI today.

Improvement is possible. Just as AIs have gotten much better at resisting prompt injection attacks over the last few years, we can safely predict that they will get better at avoiding genie-like behavior. The point of the Genie coefficient is to track progress. AI companies like benchmarks, and they all work to compete to be the best.

Dozens of benchmarks and leaderboards tell us how well these AI models write code, perform logical reasoning, and pass standardized legal and medical exams. But there is nothing that scores whether a system does what you actually meant. We need to develop a measure for this, test it regularly, and push for improvement. We’re not going to have trustworthy AI agents without it.

Measuring LLMs’ Ability to Perform Cryptanalysis

Post Syndicated from Bruce Schneier original https://www.schneier.com/blog/archives/2026/07/measuring-llms-ability-to-perform-cryptanalysis.html

There’s new benchmark measuring AI’s ability to perform mathematical cryptanalysis. Anthropic’s frontier model actually found new attacks.

The benchmark: “CryptanalysisBench: Can LLMs do Cryptanalysis?” The idea is to benchmark the ability of LLMs to discover new mathematical cryptanalytic attacks against a series of historical algorithms.

Abstract: Cryptanalysis—the task of finding attacks against cryptographic schemes—its at the intersection of mathematical reasoning and cybersecurity, two areas where LLMs have advanced fastest. Cryptanalysis represents both a clean testbed for frontier reasoning (as practical attacks can be automatically verified) and a domain with unusually high stakes, since the primitives under study underpin our digital security. In this paper we ask whether LLMs can do cryptanalysis, and find that the answer is increasingly yes. We introduce CryptanalysisBench, 191 tasks across six families of cryptographic primitives (block ciphers, hash functions, etc.) drawn primarily from four NIST standardization competitions. Our benchmark consists of three tiers: (i) primitives with known practical breaks; (ii) primitives with no known practical break, evaluated both at full strength and as scaled-down variants; and (iii) a challenge set of production primitives at the frontier of cryptanalysis. Five frontier models (Claude Opus 4.8, Sonnet 5, Mythos 5, GPT-5.5, and the open-weights GLM-5.2) break 65%­86% of Tier 1 schemes, 6­12 Tier-2 schemes at full strength, and 24­61 across all scaled-down variants. Beyond deriving known results, models produce novel cryptanalysis, such as a key-recovery attack that exploits a design flaw in the SpoC AEAD and an error in KINDI’s published CCA-security proof, both to the best of our knowledge not previously known.

We release CryptanalysisBench as a tool to help track if (or when) AI cryptanalysis becomes a serious factor and as a scaffold for stress-testing candidate schemes before deployment. The attacks that the benchmark already surfaces are an early snapshot of a fast-moving frontier that may soon match, and in places exceed, the published state of the art.

Anthropic used the benchmark to test Mythos Preview, and found new vulnerabilities in Hawk and reduced-round AES.

Still early results, but this is definitely something to watch.

SlashDot thread.