Tag Archives: GitHub Copilot

How we make AI coding more cost efficient without sacrificing task quality

Post Syndicated from Erik Kristensen original https://github.blog/ai-and-ml/github-copilot/how-we-make-ai-coding-more-cost-efficient-without-sacrificing-task-quality/


Output quality is important when working with AI coding agents, but true efficiency comes from getting work done quickly, efficiently, and with the right context.

That’s why token count of individual interactions alone isn’t a meaningful measure of efficiency. The goal shouldn’t be to use fewer tokens, but to tap into the right amount of context to move a task forward. A concise tool response can sometimes require additional calls or work if it leaves out information the agent needs, ultimately making the task slower and more expensive.

That’s why we want to optimize for the outcome rather than the tool call. This post examines four changes in GitHub Copilot that put that principle into practice:

  • Preserve useful context while reducing repetitive output.
  • Remove formatting that adds no value to the task.
  • Shorten instructions without changing useful behavior.
  • Deliver completed background work without an extra retrieval step.

Possible changes were evaluated offline using agentic coding benchmarks. The most promising changes were then validated through controlled online experiments before shipping. The examples in this post come from GitHub Copilot CLI. Multiple other Copilot products, such as the GitHub Copilot app and Copilot code review, use the same underlying harness and also become more efficient through these improvements.
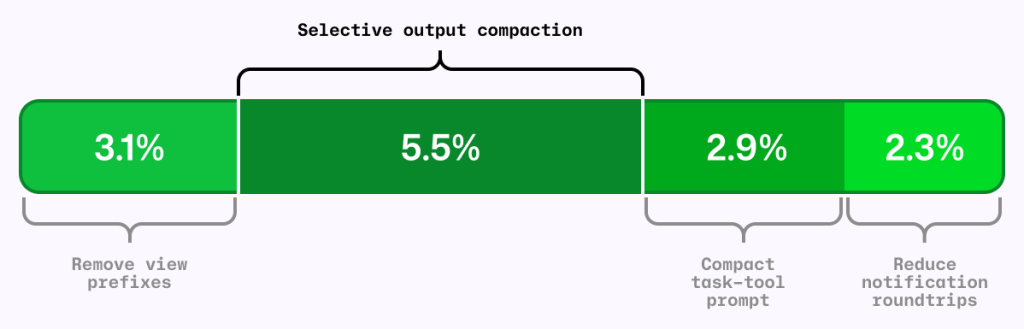
Chart showing 3.1% 'Remove view previxes', 5.5% 'Selective output compaction', 2.9% 'Compact task-tool prompt', and 2.3% 'Reduce notification roundtrips'.
Figure 1: Four independent A/B experiments using the same AI-credit metric. The segments are shown together for comparison; their effects are not necessarily strictly additive. 

The local metric trap

It’s common to shorten the output from each tool call as a way to reduce agent costs. RTK (Rust Token Killer) is a utility that shortens shell output before an agent reads it. We evaluated its effect on GitHub Copilot using our agentic coding benchmarks.

In our harness and benchmark configuration, RTK shortened some responses, but when the omitted text mattered, the model sometimes reopened the original output or reran the command to recover what it needed.

Those recovery steps added turns and carried more context forward. The individual tool response was shorter, but on average, the task used more tokens and took longer. We saved tokens locally and spent more globally.
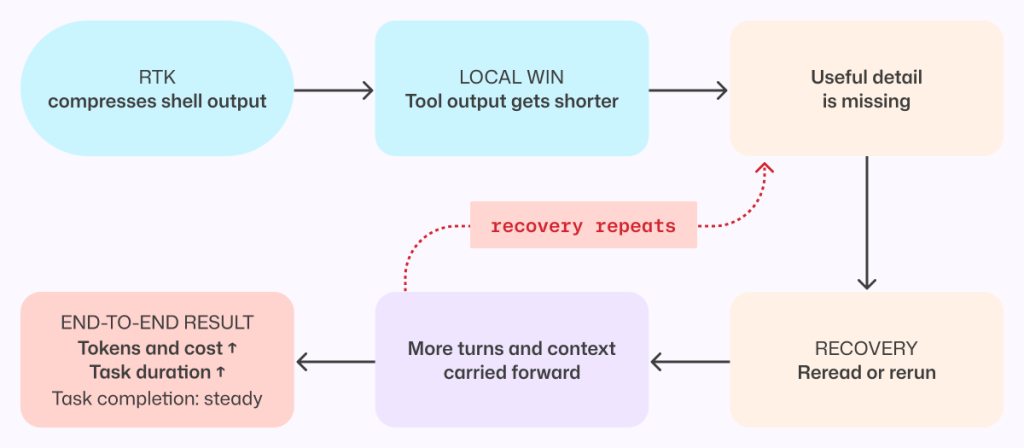
Flow chart showing: RTK, compresses shell output > Local win, tool output gets shorter > Useful detail is missing > Recovery, reread or rerun > More turns and context carried forward. Then the option of finishing at 'End-to-end result, Tokens and cost up, Task duration up, Task completion: steady,' or 'Recovery repeats' going back to 'useful detail is missing'.
Figure 2: A shorter tool response can make the completed task more expensive when missing details force the agent to reread output, rerun commands, and carry more context forward. 

This result applies to the integration and workloads we tested, not to every RTK configuration or to output compression in general. This meant that tokens per tool call is the wrong objective. An efficiency change has to be evaluated across the complete task, from the user’s request through the final result.

More useful was to look at what can we remove without making the model repeat work.

Compress noise, preserve useful information

The goal was to shorten repetitive output while preserving the context an agent needs to complete its task without retracing steps.

Analysis of benchmark runs showed that install, build, test, and lint output often contains repetitive noise, while source-like output and arbitrary command results are more likely to contain the information an agent needs. That analysis informed a selective output compressor, informed in part by RTK and similar approaches.

The prototype was evaluated on agentic coding benchmarks and a range of open source repositories, exercising their build, test, and lint systems.

Early versions were too aggressive. They made the model repeat work or read the full saved output, increasing end-to-end cost and reducing task success. For example, we initially compressed git diff but removed that filter after benchmark tasks showed agents reopening the original output to recover missing information.

Those early failures led to a three-part policy:

  1. Preserve source-like and arbitrary output. Commands such as cat, git diff, git show, and arbitrary scripts are returned unchanged.
  2. Reorganize search results without dropping content. Matches and file lists from tools such as grep can be grouped more efficiently while retaining every result.
  3. Compress repetitive noise selectively. Install, build, test, and progress output is compressed only when the savings are substantial.

The shipped version emerged through repeated evaluation and refinement. It is conservative not because the goal was to build a conservative compressor, but because that is what the evaluations supported.

When output is compressed, the agent can still retrieve the complete original through a direct recovery path.
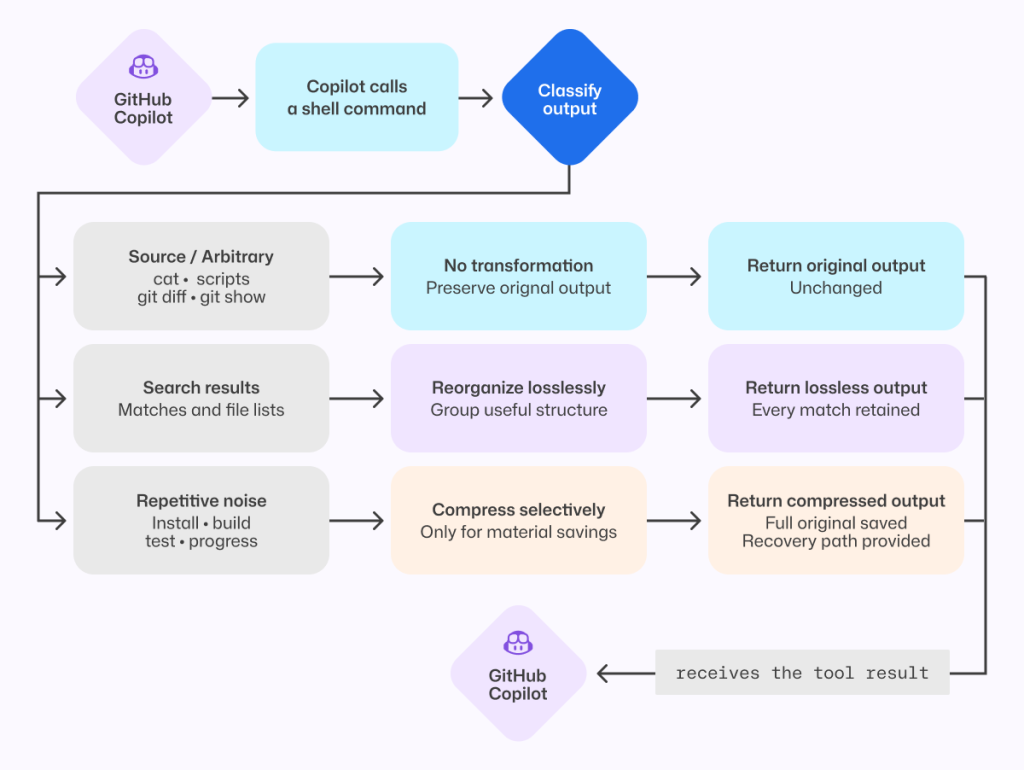
Flowchart showing how GitHub Copilot handles shell-command output. Copilot calls a shell command, classifies the output, then chooses one of three paths: keep arbitrary/source output unchanged, reorganize search results without losing any matches, or selectively compress repetitive noise (like install/build/test logs) while preserving full output and providing a recovery path. The processed result is returned to Copilot.
Figure 3: The shipped compressor preserves source-like output, reorganizes search results without loss, and compresses only predictable repetitive noise while retaining the full original.

That recovery path is both a safety mechanism and an evaluation signal. We tracked whether the agent opened the saved original, reran commands, repeated exploration, narrowed its searches, or took additional turns. Frequent recovery would indicate that the compressor had removed something valuable.

On offline tasks where output compression triggered, no statistically significant task-success regression was detected, and agents extremely rarely opened the saved originals. In the online experiment, average cost decreased slightly with no material regression detected in the tracked quality metrics.

Remove formatting before removing information

One clean token optimization came from the view tool, which agents use to read file contents into context.

Previously, view prefixed every line with a number before showing the contents to the model. Earlier file-editing tools used those numbers to target changes, but current tools instead match surrounding code and do not use line numbers. The line-number prefixes remained even though the normal workflow no longer used them.

Each prefix was small. Repeated across every line and every file read, however, that unused formatting accumulated throughout a session. So, we removed it.
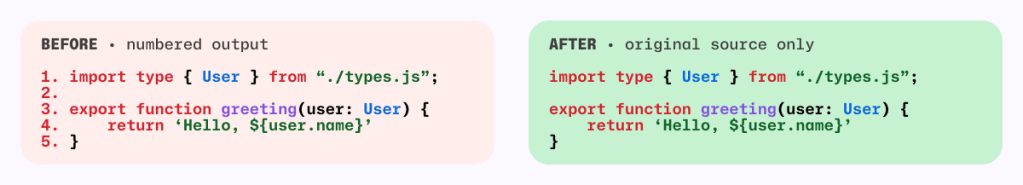
Before-and-after image of code snippets. The line-number prefixes re removed from the 'After' image.
Figure 4: Removing line-number prefixes preserves the source exactly while eliminating formatting that was repeated across every file read.

Line numbers remain useful in diffs and short snippets. They were wasteful here because they were attached to every file read without serving the current editing workflow.

Removing them caused model-inference cost to fall by roughly 5% in offline agentic coding benchmarks. Success rates stayed within the expected run-to-run variance, and edit failures did not increase.

We then tested the change with Copilot CLI users. The online experiment reduced average daily model-inference cost per user by about 3%, with no material regression detected in the quality or satisfaction metrics we tracked.

For developers, that means more of the context window is available for the work itself rather than formatting the agent does not use.

This was the ideal change: no new instructions for the model, no source of information to recover, and no additional decision to make. The file contents reached the model unchanged.

Compress prompts without compressing intent

Prompts carry instructions that shape how an agent works, and they are sent to the model on every turn. Shortening them only improves efficiency if the agent keeps the behaviors developers depend on.

In GitHub Copilot, the task tool launches specialized agents for parallel work. Its guidance had accumulated across tool descriptions, schemas, agent definitions, system instructions, and companion tools.

A meta-prompting loop, in which Copilot iteratively wrote its own prompt, reduced that prompt by roughly half. Copilot produced and refined smaller candidates, and targeted behavioral tests checked the requirements we wanted to preserve.

The first online experiment found a regression that the initial offline evaluations had missed. The meta-prompting loop had rewritten cautious parallelism guidance into a hard scheduling policy, causing independent custom agents to run sequentially.

We stopped the experiment. Before changing the prompt again, we wrote a regression evaluation for the behavior users had exposed. The eventual fix replaced an explicit allowlist and denylist with one sentence:

Independent agents can run in parallel; consider side effects.

That sentence was shorter and less restrictive; it deferred the choice of whether to run sub-agents in parallel to the model instead of the previous explicit guidance. With it, our new behavior test passed without causing any existing behavioral tests to fail.

Prompt behavior needs tests. If a behavior is not tested, a shorter prompt can remove it without anyone noticing. 
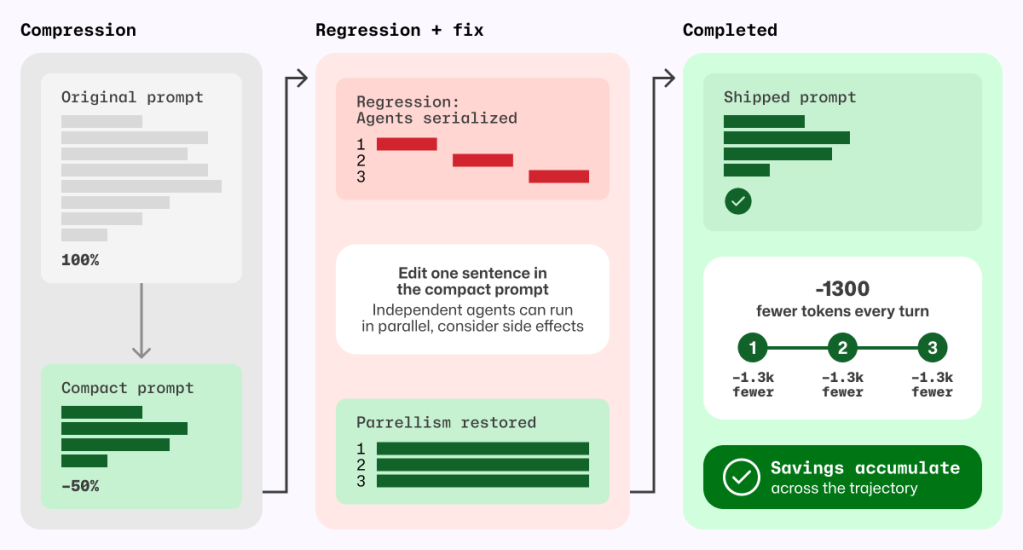
Three-stage diagram labeled Compression → Regression + fix → Completed. Left panel shows an original prompt compressed by about 50%. Middle panel highlights a regression where agents became serialized, then a fix by editing one sentence to restore parallelism. Right panel shows final shipped prompt with restored behavior and cumulative savings of about 1,300 fewer tokens per turn across steps.
Figure 5 Prompt compression became safe only after a regression test exposed serialized agents and a one-sentence fix restored parallelism; the resulting token savings recur on every model turn.

The shipped prompt removes about 1,300 task-tool prompt tokens per turn, corresponding to approximately 1.8% fewer total prompt tokens per session and 2.9% lower normalized cost per active hour, with no quality regression detected in the measured evaluations.

Deliver completed background work without an extra retrieval turn

Agents often run independent work in the background, such as a long-running shell command alongside a sub-agent investigation. Notifications let the agent continue until that work is ready without spending a tool call waiting.

If the agent does not explicitly wait for either task, the harness wakes the model and notifies it when the shell command or sub-agent finishes.

Previously, that notification did not include the completed result, so the agent had to spend another turn retrieving output Copilot had already received. When several tasks finished close together, that detour could repeat. Copilot now batches eligible completion notifications and delivers completed results directly in the existing tool-result format. The agent can continue with the information it needs, without spending an extra turn asking for it again. Explicit reads for work that is still running behave as before.
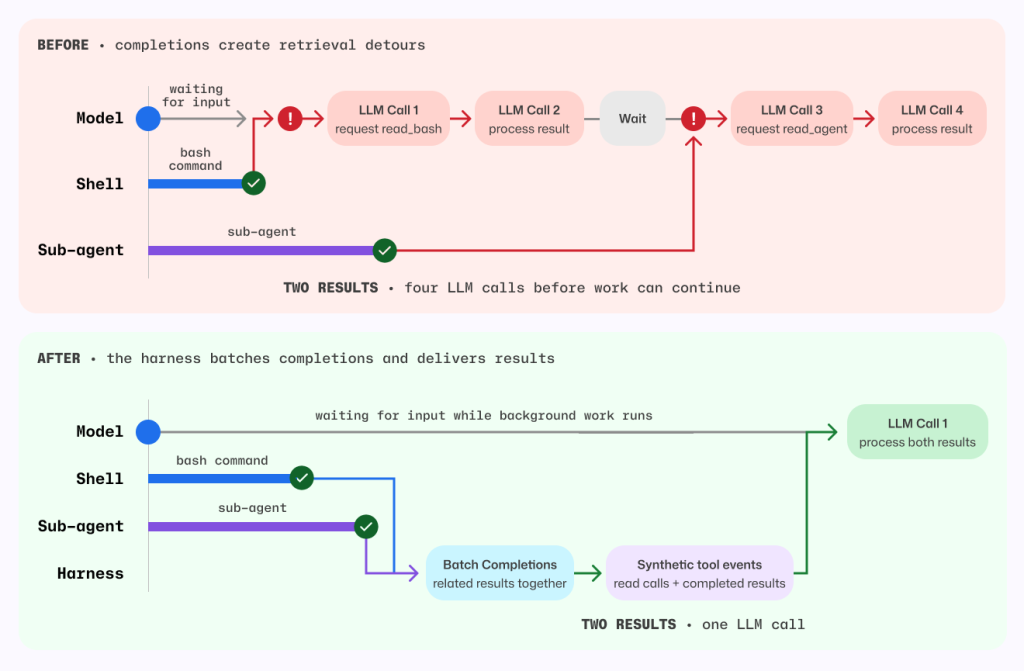
Before-and-after sequence diagram comparing orchestration behavior.

Before: model waits on separate shell and sub-agent completions, causing retrieval detours and four LLM calls to process two results.
After: a harness batches related completions and emits synthetic tool events so background work continues while waiting; both results are processed together in a single LLM call.
The visual emphasizes reduced latency and fewer model round trips.
Figure 6 Before, each background completion could wake a retrieval-only model turn. After, the harness batches eligible completions and delivers completed results in the existing tool-result format.

Before this change, each completed task required one model call to request its result and another to process it. For the shell command and sub-agent shown above, that meant four model calls before work could continue.

Now, the harness batches both completions and supplies their results together, so a single model call can process both. Removing those retrieval detours also avoids carrying the full session context through unnecessary calls.

By delivering completed results directly, without compressing, summarizing, or withholding anything, the harness reduced average token-related usage, as measured in AI Credits, by about 2.3%.

Measure changes in context

A change that saves tokens in one Copilot workflow can increase costs in another.

For example, a tighter set of file-tool instructions was inspired by positive results in Copilot code review. In a Copilot CLI online experiment, it increased cost, so we did not ship it.

By contrast, removing line-number prefixes and selectively compressing output each reduced average prompt tokens per review by roughly 5% in independent evaluations across a large set of Copilot code review tasks using the production model. We detected no material change in the tracked review-quality metrics.

These findings are separate from the earlier migration of Copilot code review to the shared file tools, which, together with review-instruction tuning, reduced code review cost by about 20%.

Each change needs to be measured in the workflow where it runs.

Five lessons for building efficient AI coding agents

  1. Optimize the completed task, not the tool call. Shorter output is not cheaper if the agent spends more turns recovering what was removed.
  2. Optimize orchestration, not just model output. Eliminate model turns that perform work the harness can complete deterministically.
  3. Compress by what the output represents. Preserve exact content, prefer lossless transformations, and measure how often agents use the recovery path.
  4. Prompt rewrites sometimes have unintended consequences. Validate that intended behavior is preserved.
  5. Evidence is local to the workload. Re-evaluate changes in offline benchmarks, online experiments, and every product surface where they ship.

None of these changes made the model smarter. They removed work the model never needed to do.

The changes described in this post are shipping across GitHub Copilot experiences that use the same underlying harness.

Bring agentic workflows to your terminal
with GitHub Copilot CLI >

The post How we make AI coding more cost efficient without sacrificing task quality appeared first on The GitHub Blog.
Better tools made Copilot code review worse. Here’s how we actually improved it.

Post Syndicated from Napalys Klicius original https://github.blog/ai-and-ml/github-copilot/better-tools-made-copilot-code-review-worse-heres-how-we-actually-improved-it/


Give an agent better tools and it should do better work. That’s the instinct, anyway.

When you open a pull request, Copilot code review reads the diff and explores the surrounding code to find the problems that matter before they ship. To do that, it used its own code exploration tools. So when we swapped in the better-maintained, shared tools that power the Copilot CLI, grep, glob, and view, we expected a clean upgrade.

Instead, in our benchmarks, we found that the cost of reviews was higher and fewer issues were being caught.

But the tools weren’t the problem. The instructions were. Once we rewrote them for the way a reviewer actually reads a pull request, the regression flipped into a win: roughly 20% lower average review cost, while maintaining the same review quality.

This is the story of how adjusting the workflows around the tools led us to a fix.

Same tools, wrong instincts

If you’ve built on top of an agent framework, you’ve probably inherited its tools too. They work, so you keep them, until the day your use case drifts far enough from what they were designed for that they quietly start working against you. That’s the situation we were in. Before trying to use the shared CLI tools, Copilot code review used its own code exploration tools. That tool layer was inspired by earlier agentic systems, including ideas from SWE-agent-style repository navigation and GitHub Copilot Autofix: list directories, search files, search directories, and read code. Those tools worked, but they were specific to Copilot code review, and they were designed for how models behaved at the time. Earlier agentic coding models made fewer tool calls and were worse at automatically pulling in necessary context. This meant it was more important to include all relevant information in the few tool calls that the model made.

Meanwhile, the Copilot CLI harness has a shared set of Unix-inspired code exploration tools: grep, glob, and view. That harness is also used by a growing number of Copilot agent products, including GitHub Copilot cloud agent, so harness improvements can benefit more than one product. We wanted to clean up and share infrastructure where possible, so we experimented with using the tools from the Copilot CLI harness in Copilot code review. The goal was to reduce duplicated tool implementations, create one shared place to improve code exploration tools, and make it easier to carry those improvements across Copilot products.

On paper, the migration looked simple:

Old Copilot code review GitHub Copilot CLI Purpose
list_dir  glob  Discover candidate files and directories before opening code. 
search_file and search_dir  grep  Search code for matching text, symbols, or call sites. 
read_code  view  Read the relevant file contents once a path or range is known. 

The existing review tools were not thin wrappers. When searching for a directory or reading a code range, they could return the matched or requested lines plus extra surrounding code context. That added token cost, but it also matched how earlier models often benefited from having nearby context included automatically.

Initially, we hoped this would be a simple migration: swap one set of tools for another. But when we tested the shared tools in offline benchmarks, the review agent became less efficient and less effective. Average cost increased, and the number of useful comments dropped.

The trace revealed a browsing loop

Our internal Copilot code review benchmarks were useful because they show more than a final score. They show the path the agent took, including which tools it called, how much output came back, where errors happened, and whether it was narrowing toward evidence or widening the search.

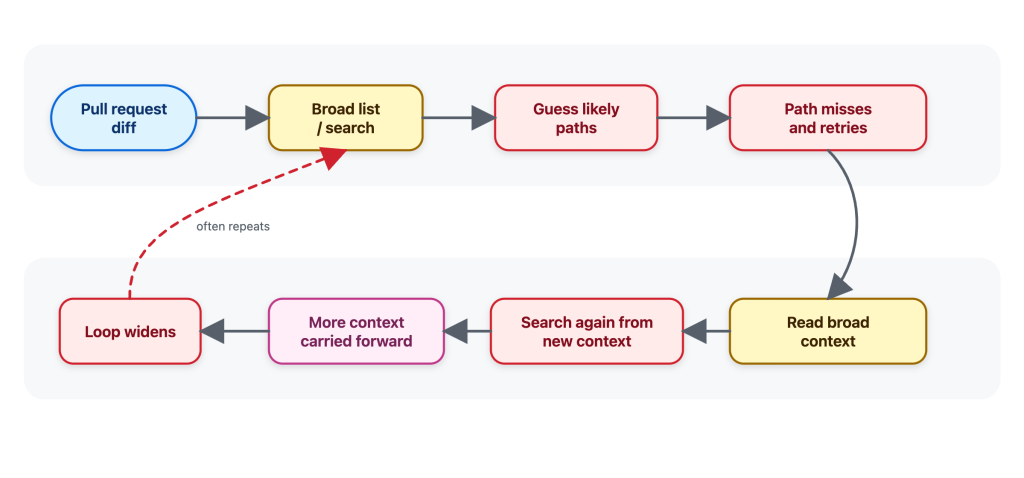
When we first tried the shared Copilot CLI tools in offline benchmarks, the agent often behaved as if it was browsing a repository instead of investigating a pull request. It would search broadly, guess likely paths, read broadly, find more things to search, and carry that extra context forward.

Diagram showing the flow before — a simplified illustration of the general-purpose behavior we observed: widening the search, guessing paths, and accumulating context.
Figure 1: Before — a simplified illustration of the general-purpose behavior we observed: widening the search, guessing paths, and accumulating context.

That pattern is understandable. Broad exploration can be useful when the task is “understand this repo.” But it’s not how a reviewer would usually review a pull request.

When I review a pull request, I start from the diff and ask targeted questions:

  • Where is this function called?
  • Is this config key used anywhere else?
  • Is there a test or helper with the same pattern?
  • What is the smallest nearby code range that explains this behavior?

I do not want to open a large part of the repository before I know what I am looking for. I want the minimal context needed to answer the question, without overloading the review with unrelated code.

That matters because every tool result becomes part of the agent’s working context. Extra file contents can be carried forward into later reasoning, increasing cost and sometimes making the review less focused. A tool result is not a disposable printout; for an agent, it’s extra tokens that stay in the context window.

The traces made that difference visible. The shared tools were not the problem. The instructions were giving the agent the wrong instincts to do an efficient and effective review.

The tools themselves worked, but their instructions were tuned for their use within the Copilot CLI and implied the wrong workflow: the agent used grep, glob, and view like a broad coding assistant instead of a reviewer. A coding assistant may map a whole area before making a change to ensure it doesn’t break some other corner of the code. On the other hand, a reviewer usually starts from the diff, asks whether the change introduced a problem, and then looks for the narrowest nearby evidence required to confirm or dismiss it.

General coding-assistant tool instructions, like the ones used by Copilot CLI or Copilot cloud agent, make sense for an interactive assistant. A developer may ask it to understand a repository, plan a change, edit files, and continue over multiple turns.

Copilot code review has a narrower job: start from a pull request diff, gather enough surrounding evidence to decide whether a change introduces a real issue, and avoid loading context that is not needed for that review question.

It was therefore clear that we couldn’t simply replace the previous Copilot code review tools with the tools from the Copilot CLI without additional prompting work. The problem became: how do we design tool instructions that use these shared tools effectively in a code review setting?

Rewriting the tool instructions for a reviewer’s workflow

The next iterations made the guidance specific to code review. The workflow we wanted Copilot code review to follow was:

  1. Start from the diff and form specific review questions.
  2. Use glob when the path is uncertain and grep to find candidate files, symbols, and call sites.
  3. Batch cheap discovery before reading files.
  4. Use view only when the agent knows which file or line range it needs.
  5. Batch focused reads instead of alternating between one search and one read.

In oversimplified form, this was the behavior we encoded:

Generic posture: Use the available tools to inspect repository context that may be relevant.

Review-shaped guidance: Start from the diff. Narrow first with grep and glob; read exact evidence with view. If grep fails to find relevant context, retry with a simpler escaped search. If a path is wrong, pivot to glob instead of guessing nearby paths.

For example, imagine the diff changes an authorization helper that decides whether an operation is allowed. A relevant review question is not “show me the full contents of every file that calls this helper.” It could instead be the narrower: “are any request-handling callers relying on the old behavior?”

The intended path is short:

start from the helper changed in the diff 
grep for callers of that helper 
glob for likely route, handler, or controller files 
view the most relevant caller ranges 
decide whether any caller changes the risk

The guidance also changed how the agent recovered from failed searches. If an input made grep fail, the better next step was one simpler, corrected search. If a path was wrong, the better next step was glob, not guessing neighboring paths and reading whatever happened to exist. That nudged the agent away from letting a small tool failure turn into a larger exploration loop.

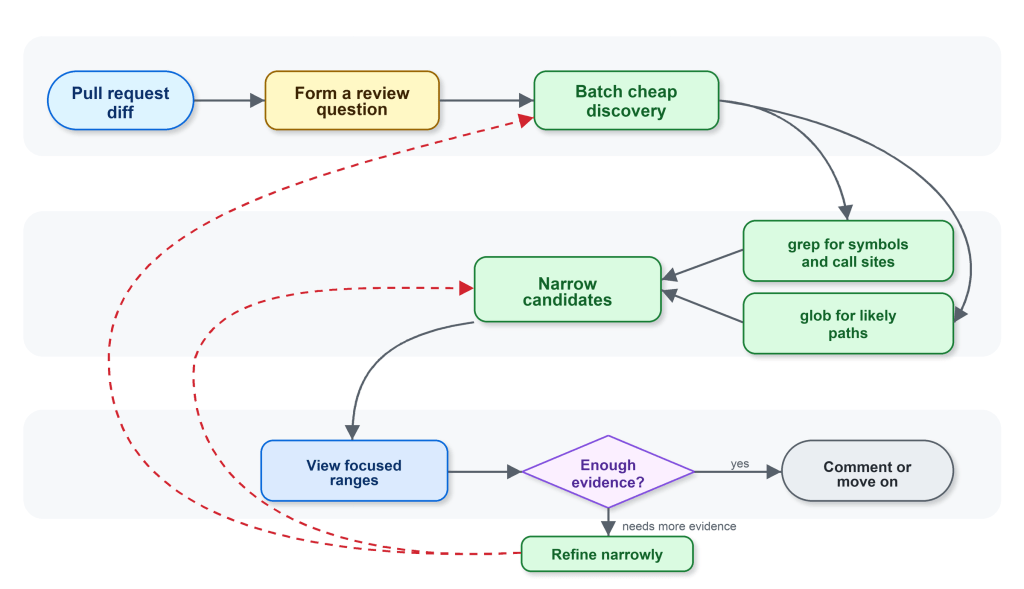
Diagram showing the flow after: a simplified illustration of the review-shaped behavior the prompt guided toward: stay anchored to the diff, narrow with grep and glob, then read focused ranges with view.
Figure 2: After — a simplified illustration of the review-shaped behavior the prompt guided toward: stay anchored to the diff, narrow with grep and glob, then read focused ranges with view.

The change was small in wording and large in effect. It changed the rhythm of the agent from “browse, read, search again” to “ask, narrow, read, decide.”

Benchmarks let us debug behavior, not just scores

The shared harness gave us the tools. The internal Copilot code review benchmarks gave us the feedback loop.

We could run the same review examples, compare tool traces, update the instructions, and run again. That let us ask concrete questions:

  • Did the agent narrow first, or read broadly first?
  • Did it batch independent searches?
  • Did it call view only when it had a reason?
  • Did a tool-instruction change reduce tool errors, or just move them somewhere else?
  • Did the trace stay focused on evidence from the diff?
  • Did the review still preserve the quality metrics we cared about?

The most useful signal was not “the instructions are better.” It was more concrete. The agent was making a similar number of tool calls, but spending more of them on relevant evidence instead of repeatedly expanding the search.

That connected product-level outcomes to understandable engineering behavior. Instead of guessing why a score moved, we could inspect the workflow that produced it.

The result: roughly 20% lower average review cost

In production, the tuned behavior showed roughly 20% lower average review cost compared with the control. Importantly, it did not show a quality signal that could block shipping.

The reduction did not come from the tools by themselves, it came from the workflow around them. Shared code exploration tools, Copilot code review custom tool instructions, and internal benchmarks made the agent’s behavior visible enough to tune.

That framing matters when building with agents. It can be tempting to treat tools as implementation details by swapping one tool for another, then comparing the final answer. But for an agent, the tool surface is part of the product experience. It changes what the agent notices, how it searches, how much context it carries forward, and when it decides it has enough evidence.

Tool descriptions and system instructions are closer to API documentation. Unclear API docs can leave a developer confused and lead to inefficient or wrong decisions. Unclear tool prompting can do the same for an LLM; a small wording change can affect cost, quality, and the shape of the investigation because it changes how the agent spends its attention.

Same tools, different job

We also tried to apply the same kind of focused tool instructions in the CLI, where it did not produce the same kind of win. That is a useful counterexample, and an important guardrail for the lesson.

Copilot code review is anchored to a diff and a review question. Copilot CLI handles broader, interactive coding tasks where exploration can be part of the job. There may be no single diff anchor, the user may change direction over multiple turns, and the right context may not be obvious at the start. The same grep, glob, and view tools can support both products, but the workflow around those tools has to match the product.

The takeaway is that shared tools scale when the instructions and benchmarks match the job.

Try it out yourself using GitHub Copilot code review.

The post Better tools made Copilot code review worse. Here’s how we actually improved it. appeared first on The GitHub Blog.

Automating cross-repo documentation with GitHub Agentic Workflows

Post Syndicated from David Pine original https://github.blog/ai-and-ml/github-copilot/automating-cross-repo-documentation-with-github-agentic-workflows/


“Where are the docs?” It’s a question nobody on a product team enjoys answering. The honest reply is usually some variant of “behind.” A writer is staring at a closed pull request, trying to reverse-engineer what changed. The pull request’s author has already moved on. By the time the doc actually publishes, the feature has shipped, sometimes more than once.

That used to be us on the Aspire team (we’re a small team of 10 building dev tools for distributed apps). A few months back, we were trying to figure out how to safely bring AI into automations we already trusted. That’s when we discovered GitHub Agentic Workflows. I started bolting prototypes into microsoft/aspire.

Here’s what that bought us, in numbers pulled straight out of GitHub: for Aspire 13.3 and 13.4, 82 feature-docs pull requests merged at a median of 44.8 hours after the product pull request, every one of them reviewed by the engineer who shipped the feature. No new headcount. No process retraining. Just a different way of asking “who writes this?”

🔒 The constraint: cross-repo automation is the hard part

Our product lives in microsoft/aspire and our docs site lives in microsoft/aspire.dev—different repo, deploy target, and review chain. Most teams figure out same-repo automation pretty quickly; cross-repo automation is where things get sharp. Broad repo-scoped tokens belong in a museum, and any responsible security posture (ours included) restricts them accordingly. That’s a good thing. It’s also a real bottleneck if the place where you write the docs isn’t the place where you write the code.

The default workflow for years was:

  1. Engineer ships a feature in microsoft/aspire.
  2. Docs writer notices weeks later.
  3. Docs writer opens the pull request, reads the diff, and pings the engineer to clarify what changed.
  4. Engineer is on the next feature, vaguely remembers, replies with half the picture.
  5. Docs draft ships, sometimes against a release that’s already out.

This is the reverse-engineering tax. We needed automation that crossed repos without handing an agent a write-everywhere token. GitHub Agentic Workflows turned out to be the answer.

🤖 Why GitHub Agentic Workflows

GitHub Agentic Workflows is a project from the GitHub Next team that I keep describing to people as “GitHub Actions, but with a model as the work-item processor and guard rails that satisfy security review.” That’s reductive, but it’s close.

The shape of it:

  • You author a workflow as a single markdown file (.github/workflows/my-thing.md). YAML-style frontmatter on top, an English-language prompt underneath.
  • You run GitHub Agentic Workflows compile, and it generates a sibling .lock.yml (a normal GitHub Actions workflow) that you commit alongside.
  • At runtime, the workflow runs an agent against your prompt with a constrained toolset.
  • Critically, the agent doesn’t write to GitHub directly. It emits intent (a JSON blob describing the pull requests, issues, and comments it wants to create), and a separate, narrowly scoped job (the safe-outputs handler) materializes that intent against a per-workflow GitHub app.

That last bullet is the unlock. The agent gets read access and a prompt. Writes go through a tiny verifiable pipeline with explicit allow-lists. Security review nods. We ship.

💚 A small aside: kindred stacks

I love when the tools you’re using to build are built with the same tools you’re using to build with. The GitHub Agentic Workflows docs are built with Astro and Starlight. So is aspire.dev—Astro with Starlight, dressed up with the wider Starlight plugin ecosystem (astro-mermaid, starlight-llms-txt, starlight-sidebar-topics, starlight-image-zoom, the gorgeous @catppuccin/starlight theme, and more. Shout-out to Chris Swithinbank and the Starlight maintainers, the entire ecosystem feels designed by people who genuinely care).

There’s a real kinship there. The tool we use to automate docs and the docs site we automate into share the same foundation. Convenient, because the Mermaid sequence diagram in the next section renders the exact same way in both worlds.

The end-to-end pipeline

Here’s the flow we landed on. The protagonist is a workflow called pr-docs-check.md living in microsoft/aspire.

Sequence diagram showing an automated docs workflow: merging a feature pull request in microsoft/aspire triggers a GitHub Actions check that has an agent draft the documentation, open a draft pull request in microsoft/aspire.dev, and request SME review—so docs ship with the feature.

A run starts on pull_request: closed against main or release/*, gated by merged == true. From there, the workflow first runs a deterministic target branch resolver in plain bash before the agent ever wakes up:

  1. Pull request milestone title (e.g. 13.4 → release/13.4 on aspire.dev).
  2. Linked-issue milestone title (parse Fixes/Closes/Resolves #N from the body, fetch each issue, take the first non-empty milestone).
  3. Pull request base ref, if it matches release/X.Y[.Z].
  4. Fall back to main.

This is the linchpin. Milestones in the product repo map cleanly to release branches in the docs repo. When the agent finally runs, it knows exactly where the docs should land without any creative writing about target branches or guessing.

The agent reads the diff, scans linked issues, and decides: does this need docs? If yes, it drafts the actual content in a checked-out microsoft/aspire.dev workspace, following our existing doc-writer skill (voice, MDX conventions, Starlight components). It then emits a create_pull_request safe-output and hands off.

The safe-outputs handler takes over:

  • Title prefix: [docs]
  • Label: docs-from-code
  • draft: true (we never auto-merge)
  • Base branch: agent-supplied, restricted to main or release/*
  • Target repo: microsoft/aspire.dev
  • Reviewer: the SME identified from the source pull request’s reviews—i.e., whoever the product team trusted to approve the feature, now gets asked to approve the doc for that feature.

A companion job posts a marker comment back on the source pull request with the docs pull request link and minimizes any older pr-docs-check comments on re-run. The engineer who just hit Merge gets a notification within a few minutes: “Here’s the docs draft. Look it over?”

🔐 The safe-outputs contract

The whole security story comes down to a small, boring stretch of frontmatter:

tools: 
  github: 
    toolsets: [repos, issues, pull_requests] 
    min-integrity: approved          # only run pinned, integrity-checked actions 
    allowed-repos: 
      - microsoft/* 
    github-app: 
      app-id: ${{ secrets.ASPIRE_BOT_APP_ID }} 
      private-key: ${{ secrets.ASPIRE_BOT_PRIVATE_KEY }} 
      owner: "microsoft" 
      repositories: ["aspire.dev", "aspire"] 

safe-outputs: 
  create-pull-request: 
    title-prefix: "[docs] " 
    labels: [docs-from-code] 
    draft: true                      # human-in-the-loop, always 
    base-branch: main 
    allowed-base-branches: [main, release/*] 
    target-repo: "microsoft/aspire.dev" 
    protected-files: blocked         # AGENTS.md, manifests, security config: hands off 
    fallback-as-issue: true 

That’s the deal in plain text. The agent gets a GitHub App token whose installation is scoped to exactly two repositories—the product repo and the docs repo—and nothing else in the org is reachable. It can only land pull requests against main or release/*. AGENTS.md and dependency manifests are off-limits by policy. If the pull request creation fails (network blip, conflict, anything), the framework falls back to filing an issue, so nothing is silently dropped.

This is the part security review actually liked. The agent’s reasoning is fuzzy. The action surface is not.

📊 By the numbers

Here are the stats from a rolling 30-day window (May 3 – June 2, 2026) spanning the back end of the Aspire 13.3 release and the run-up to 13.4:

Metric  Value 
Product pull requests merged in microsoft/aspire  396 (338 main / 50 release/13.3 / 8 release/13.2) 
pr-docs-check workflow runs  396 
Draft docs pull requests created on microsoft/aspire.dev  82 
  – Merged  82 (100%) 
  – Closed without merge 
  – Still open 
Docs pull requests target branches  52 → release/13.3, 27 → release/13.4, 3 → main 
Median time-to-merge (docs)  44.8 hours 
Merged within 24 h / 7 days  38% / 96% 

Note: Numbers captured at the time of writing; the workflows keep running, so the totals only go up. 

A few of those numbers deserve a second look:

  • 396 runs → 82 pull requests is not a defect. The workflow runs on every merged pull request; most of them are internal refactors, test fixes, or dependency bumps with no user-facing surface. The agent saying “no docs needed” 300+ times is a feature.
  • 100% merge rate says the agent’s docs picks are right. The tighter prompt we shipped after the v1 false-positive phase is paying off.

✅ What worked, what didnt

What worked

  • Milestone → release-branch mapping. This was the single highest-leverage choice we made. Engineers already set milestones on pull requests and issues; we got accurate target-branch routing for free.
  • Draft-only, SME-as-reviewer. The agent never merges. The engineer who shipped the feature is the one who confirms the docs are right. We’ve stopped reverse-engineering features at the doc layer. The engineer just tells the docs draft what to say, in the place where they already are.
  • Scoped GitHub app per workflow. Each workflow gets its own app token with explicit repo and permission scopes. Security review approved. We approved too; the first time we needed to rotate keys.
  • protected-files: blocked. The agent cannot touch AGENTS.md, package manifests, or repo security config. Period.

What didn’t (at first)

  • ❌ The agent’s “is this docs-worthy?” gate was too generous in the first version. It drafted pull requests for changes that were genuinely internal, such as a CI tweak or a logging refactor. The result: 9 closures of 69 pull requests (≈13%), so we tightened the prompt’s user-facing-change definition and added explicit negative examples (CI, internal helpers, tests-only). Now, the rate is trending down.
  • ❌ Cross-repo pull request creation needed a mirrored checkout pattern that wasn’t obvious from the docs. The agent works in one repo; safe-outputs needs to find the target repo to push a branch. We solved it by checking out microsoft/aspire.dev twice—once as the current workspace, once under _repos/aspire.dev—so the safe-outputs handler can rediscover it deterministically.
  • ❌ Big diffs blow prompt budgets. We pre-extract pull request metadata (linked issues, milestone, base ref) in pre-agent-steps bash, so the agent gets a small, structured summary instead of a giant payload. This is GitHub Agentic Workflow’s designed-in pattern, and it works.

Wrapping up

The changes we made shifted our thinking. A feature wasn’t considered done until the docs were. Docs no longer trail along behind it like a tin can on a string. The engineer’s review is the gate; the bot does the typing.

Critically, this doesn’t replace docs writers; it un-burdens them. Our writers used to spend most of their time reverse-engineering features. Now they spend their time on the things only a human can do well: narrative pages, sample programs, conceptual walkthroughs, the parts of the docs that don’t fall out of a diff. The bot handles the mechanical “this new option was added; here’s the reference page update” work that was never enjoyable for anyone.

Huge thanks to the GitHub Next team for GitHub Agentic Workflows (and for making the safe-outputs primitive a first-class part of the design), and to Chris Swithinbank and the Starlight maintainers for the docs platform we automate into. A genuine thank-you, too, to the security folks whose guardrails forced us to design this the right way the first time. The boring secret of good automation is that strong security constraints make the system more trustworthy and more correct.

If you build a product in one repo and ship docs in another—and especially if you have to do it inside any nontrivial security boundary—GitHub Agentic Workflows is worth a serious look. Start with one workflow, such as pr-docs-check, and watch what happens to your median time-to-docs.

🔗 The other workflows

pr-docs-check is the one I wrote this post about, but it’s not running alone. If you’re curious about the rest, the source is public:

  • milestone-changelog.md: runs every two hours, picks up newly merged pull requests in the active milestone, and maintains a 13.x-Change-log wiki page (new features, improvements, notable bug fixes) with a companion editorial-feedback issue. 346 runs.
  • release-update-support-mdx.md: on a stable Aspire release, drafts a [support] pull request on aspire.dev that updates the support policy page (promotes the new version, demotes the previous one, refreshes the “Last updated” badge).
  • update-integration-data.md: lives in the docs repo; runs pnpm update:all daily, refreshes NuGet metadata + GitHub stats + sample data, and opens a chore: Update integration data PR with supersede-and-close logic for stale runs. 27 runs, eight merged pull requests.
  • repo-pulse.md: a rolling three-day repo dashboard pinned to a single issue and updated in place: recent merges, pull requests awaiting review, new issues, discussion activity. One issue, always fresh.

Happy automating, friends! 🤖🚀

The post Automating cross-repo documentation with GitHub Agentic Workflows appeared first on The GitHub Blog.

Agent-driven development in Copilot Applied Science

Post Syndicated from Tyler McGoffin original https://github.blog/ai-and-ml/github-copilot/agent-driven-development-in-copilot-applied-science/


I may have just automated myself into a completely different job…

This is a familiar pattern among software engineers, who often, through inspiration, frustration, or sometimes even laziness, build systems to remove toil and focus on more creative work. We then end up owning and maintaining those systems, unlocking that automated goodness for the rest of those around us.

As an AI researcher, I recently took this beyond what was previously possible and have automated away my intellectual toil. And now I find myself maintaining this tool to enable all my peers on the Copilot Applied Science team to do the same.

During this process, I learned a lot about how to effectively create and collaborate using GitHub Copilot. Applying these learnings has unlocked an incredibly fast development loop for myself as well as enabled my team mates to build solutions to fit their needs.

Before I get into explaining how I made this possible, let me set the stage for what spawned this project so you better understand the scope of what you can do with GitHub Copilot.

The impetus

A large part of my job involves analyzing coding agent performance as measured against standardized evaluation benchmarks, like TerminalBench2 or SWEBench-Pro. This often involves poring through tons of what are called trajectories, which are essentially lists of the thought processes and actions agents take while performing tasks.

Each task in an evaluation dataset produces its own trajectory, showing how the agent attempted to solve that task. These trajectories are often .json files with hundreds of lines of code. Multiply that over dozens of tasks in a benchmark set and again over the many benchmark runs needing analysis on any given day, and we’re talking hundreds of thousands of lines of code to analyze.

It’s an impossible task to do alone, so I would typically turn to AI to help. When analyzing new benchmark runs, I found that I kept repeating the same loop: I used GitHub Copilot to surface patterns in the trajectories then investigated them myself—reducing the number of lines of code I had to read from hundreds of thousands to a few hundred.

However, the engineer in me saw this repetitive task and said, “I want to automate that.” Agents provide us with the means to automate this kind of intellectual work, and thus eval-agents was born.

The plan

Engineering and science teams work better together. That was my guiding principle as I set about solving this new challenge.

Thus, I approached the design and implementation strategy of this project with a couple of goals in mind:

  1. Make these agents easy to share and use
  2. Make it easy to author new agents
  3. Make coding agents the primary vehicle for contributions

Bullets one and two are in GitHub’s lifeblood and are values and skills I’ve gained throughout my career, especially during my stint as an OSS maintainer on the GitHub CLI.

However, goal three shaped the project the most. I noticed that when I set GitHub Copilot up to help me build the tool effectively, it also made the project easier to use and collaborate on. That experience taught me a few key lessons, which ultimately helped push the first and second goals forward in ways I didn’t expect.

Making coding agents your primary contributor

I’ll start by describing my agentic coding setup:

  • Coding agent: Copilot CLI
  • Model used: Claude Opus 4.6
  • IDE: VSCode

It’s also noteworthy that I leveraged the Copilot SDK to accelerate agent creation, which is powered under the hood by the Copilot CLI. This gave me access to existing tools and MCP servers, a way to register new tools and skills, and a whole bunch of other agentic goodness out of the box that I didn’t have to reinvent myself.

With that out of the way, I could streamline the whole development process very quickly by following a few core principles:

  • Prompting strategies: agents work best when you’re conversational, verbose, and when you leverage planning modes before agent modes.
  • Architectural strategies: refactor often, update docs often, clean up often.
  • Iteration strategies: “trust but verify” is now “blame process, not agents.”

Uncovering and following these strategies led to an incredible phenomenon: adding new agents and features was fast and easy. We had five folks jump into the project for the first time, and we created a total of 11 new agents, four new skills, and the concept of eval-agent workflows (think scientist streams of reasoning) in less than three days. That amounted to a change of +28,858/-2,884 lines of code across 345 files.

Holy crap!

Below, I’ll go into detail about these three principles and how they enabled this amazing feat of collaboration and innovation.

Prompting strategies

We know that AI coding agents are really good at solving well-scoped problems but need handholding for the more complex problems you’d only entrust to your more senior engineers.

So, if you want your agent to act like an engineer, treat it like one. Guide its thinking, over-explain your assumptions, and leverage its research speed to plan before jumping into changes. I found it far more effective to put some stream-of-consciousness musings about a problem I was chewing on into a prompt and working with Copilot in planning mode than to give it a terse problem statement or solution.

Here’s an example of a prompt I wrote to add more robust regression tests to the tool:

> /plan I've recently observed Copilot happily updating tests to fit its new paradigms even though those tests shouldn't be updated. How can I create a reserved test space that Copilot can't touch or must reserve to protect against regressions?

This resulted in a back and forth that ultimately led to a series of guardrails akin to contract testing that can only be updated by humans. I had an idea of what I wanted, and through conversation, Copilot helped me get to the right solution.

It turns out that the things that make human engineers the most effective at doing their jobs are the same things that make these agents effective at doing theirs.

Architectural strategies

Engineers, rejoice! Remember all those refactors you wanted to do to make the codebase more readable, the tests you never had time to write, and the docs you wish had existed when you onboarded? They’re now the most important thing you can be working on when building an agent-first repository.

Gone are the days where deprioritizing this work over new feature work was necessary, because delivering features with Copilot becomes trivial when you have a well-maintained, agent-first project.

I’ve spent most of my time on this project refactoring names and file structures, documenting new features or patterns, and adding test cases for problems that I’ve uncovered as I go. I’ve even spent a few cycles cleaning up the dead code that the agents (like your junior engineers) may have missed while implementing all these new features and changes.

This work makes it easy for Copilot to navigate the codebase and understand the patterns, just like it would for any other engineer.

I can even ask, “Knowing what I know now, how would I design this differently?” And I can then justify actually going back and rearchitecting the whole project (with the help of Copilot, of course).

It’s a dream come true!

And this leads me to my last bit of guidance.

Iteration strategies

As agents and models have improved, I have moved from a “trust but verify” mindset to one that is more trusting than doubtful. This mirrors how the industry treats human teams: “blame process, not people.” It’s how the most effective teams operate, because people make mistakes, so we build systems around that reality.

This idea of blameless culture provides psychological safety for teams to iterate and innovate, knowing that they won’t be blamed if they make a mistake. The core principle is that we implement processes and guardrails to protect against mistakes, and if a mistake does happen, we learn from it and introduce new processes and guardrails so that our teams won’t make the same mistake again.

Applying this same philosophy to agent-driven development has been fundamental to unlocking this incredibly rapid iteration pipeline. That means we add processes and guardrails to help prevent the agent from making mistakes, but when it does make a mistake, we add additional guardrails and processes—like more robust tests and better prompts—so the agent can’t make the same mistake again. Taking this one step further means that practicing good CI/CD principles is a must.

Practices like strict typing ensure the agent conforms to interfaces. Robust linters impose implementation rules on the agent that keep it following good patterns and practices. And integration, end-to-end, and contract tests—which can be expensive to build manually—become much cheaper to implement with agent assistance, while giving you confidence that new changes don’t break existing features.

When Copilot has these tools available in its development loop, it can check its own work. You’re setting it up for success, much in the same way you’d set up a junior engineer for success in your project.

Putting it all together

Here’s what all this means for your development loop when you’ve got your codebase set up for agent-driven development:

  1. Plan a new feature with Copilot using /plan.
    • Iterate on the plan.
    • Ensure that testing is included in the plan.
    • Ensure that docs updates are included in the plan and done before code is implemented. These can serve as additional guidelines that live beside your plan.
  2. Let Copilot implement the feature on /autopilot.
  3. Prompt Copilot to initiate a review loop with the Copilot Code Review agent. For me, it’s often something like: request Copilot Code Review, wait for the review to finish, address any relevant comments, and then re-request review. Continue this loop until there are no more relevant comments.
  4. Human review. This is where I enforce the patterns I discussed in the previous sections.

Additionally, outside of your feature loop, be sure you’re prompting Copilot early and often with the following:

  • /plan Review the code for any missing tests, any tests that may be broken, and dead code
  • /plan Review the code for any duplication or opportunities for abstraction
  • /plan Review the documentation and code to identify any documentation gaps. Be sure to update the copilot-instructions.md to reflect any relevant changes

I have these run automatically once a week, but I often find myself running them throughout the week as new features and fixes go in to maintain my agent-driven development environment.

Take this with you

What started as a frustration with an impossibly repetitive analysis task turned into something far more interesting: a new way of thinking about how we build software, how we collaborate, and how we grow as engineers.

Building agents with a coding agent-first mindset has fundamentally changed how I work. It’s not just about the automation wins—though watching four scientists ship 11 agents, four skills, and a brand-new concept in under three days is nothing short of remarkable. It’s about what this style of development forces you to prioritize: clean architecture, thorough documentation, meaningful tests, and thoughtful design—the things we always knew mattered but never had time for.

The analogy to a junior engineer keeps proving itself out. You onboard them well, give them clear context, build guardrails so their mistakes don’t become disasters, and then trust them to grow. If something goes wrong, you blame the process. Not the agent. If there’s one thing I want you to take away from this, it’s that the skills that make you a great engineer and a great teammate are the same skills that make you great at building with Copilot. The technology is new. The principles aren’t.

So go clean up that codebase, write that documentation you’ve been putting off, and start treating your Copilot like the newest member of your team. You might just automate yourself into the most interesting work of your career.

Think I’m crazy? Well, try this:

  1. Download Copilot CLI
  2. Activate Copilot CLI in any repo: cd <repo_path> && copilot
  3. Paste in the following prompt: /plan Read <link to this blog post> and help me plan how I could best improve this repo for agent-first development

The post Agent-driven development in Copilot Applied Science appeared first on The GitHub Blog.

Continuous AI for accessibility: How GitHub transforms feedback into inclusion

Post Syndicated from Carie Fisher original https://github.blog/ai-and-ml/github-copilot/continuous-ai-for-accessibility-how-github-transforms-feedback-into-inclusion/


For years, accessibility feedback at GitHub didn’t have a clear place to go.

Unlike typical product feedback, accessibility issues don’t belong to any single team—they cut across the entire ecosystem. For example, a screen reader user might report a broken workflow that touches navigation, authentication, and settings. A keyboard-only user might hit a trap in a shared component used across dozens of pages. A low vision user might flag a color contrast issue that affects every surface using a shared design element. No single team owns any of these problems—but every one of them blocks a real person.

These reports require coordination that our existing processes weren’t originally built for. Feedback was often scattered across backlogs, bugs lingered without owners, and users followed up to silence. Improvements were often promised for a mythical “phase two” that rarely materialized.

We knew we needed to change this. But before we could build something better, we had to lay the groundwork—centralizing scattered reports, creating templates, and triaging years of backlog. Only once we had that foundation in place could we ask: How can AI make this easier?

The answer was an internal workflow, powered by GitHub Actions, GitHub Copilot, and GitHub Models, that ensures every piece of user and customer feedback becomes a tracked, prioritized issue. When someone reports an accessibility barrier, their feedback is captured, reviewed, and followed through until it’s addressed. We didn’t want AI to replace human judgment—we wanted it to handle repetitive work so humans could focus on fixing the software.

This is how we went from chaos to a system where every piece of accessibility feedback is tracked, prioritized, and acted on—not eventually, but continuously.

Accessibility as a living system

Continuous AI for accessibility weaves inclusion into the fabric of software development. It’s not a single product or a one-time audit—it’s a living methodology that combines automation, artificial intelligence, and human expertise.

This philosophy connects directly to our support for the 2025 Global Accessibility Awareness Day (GAAD) pledge: strengthening accessibility across the open source ecosystem by ensuring user and customer feedback is routed to the right teams and translated into meaningful platform improvements.

The most important breakthroughs rarely come from code scanners—they come from listening to real people. But listening at scale is hard, which is why we needed technology to help amplify those voices. We built a feedback workflow that functions less like a static ticketing system and more like a dynamic engine—leveraging GitHub products to clarify, structure, and track user and customer feedback, turning it into implementation-ready solutions.

Designing for people first

Before jumping into solutions, we stepped back to understand who this system needed to serve:

  • Issue submitters: Community managers, support agents, and sales reps submit issues on behalf of users and customers. They aren’t always accessibility experts, so they need a system that guides them and teaches accessibility concepts in the flow of work.
  • Accessibility and service teams: Engineers and designers responsible for fixes need structured, actionable data—reproducible steps, WCAG mapping, severity scores, and clear ownership.
  • Program and product managers: Leadership needs visibility into pain points by category, trends, and progress over time to allocate resources strategically.

With these personas in mind, we knew we wanted to 1) treat feedback as data flowing through a pipeline and 2) build a system able to evolve with us.

How feedback flows

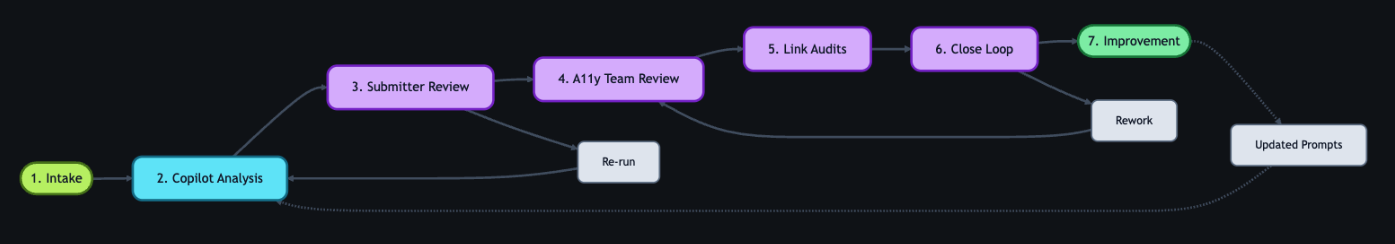
With that foundation set, we built an architecture around an event-driven pattern, where each step triggers a GitHub Action that orchestrates what comes next—ensuring consistent handling no matter where the feedback originates. We built this system largely by hand starting in mid-2024. Today, tools like Agentic Workflows let you create GitHub Actions using natural language—meaning this kind of system could be built in a fraction of the time.

The workflow reacts to key events: Issue creation launches GitHub Copilot analysis via the GitHub Models API, status changes initiate hand-offs between teams, and resolution triggers submitter follow-up with the user. Every Action can also be triggered manually or re-run as needed—automation covers the common path, while humans can step in at any point.

Feedback isn’t just captured—it continuously flows through the right channels, providing visibility, structure, and actionability at every stage.

*Click images to enlarge.

A left-to-right flowchart showing the seven steps of the feedback workflow in sequence: Intake, Copilot Analysis, Submitter Review, Accessibility Team Review, Link Audits, Close Loop, and Improvement. Feedback loops show that Submitter Review can re-run Copilot Analysis, Close Loop can return to Accessibility Team Review, and Improvement feeds updated prompts back to Copilot Analysis.

1. Actioning intake

Feedback can come from anywhere—support tickets, social media posts, email, direct outreach—but most users choose the GitHub accessibility discussion board. It’s where they can work together and build community around shared experiences. Today, 90% of the accessibility feedback flows through that single channel. Because posts are public, other users can confirm the problem, add context, or suggest workarounds—so issues often arrive with richer detail than a support ticket ever could. Regardless of the source, every piece of feedback gets acknowledged within five business days, and even feedback we can’t act on gets a response pointing to helpful resources.

When feedback requires action from internal teams, a team member manually creates a tracking issue using our custom accessibility feedback issue template. Issue templates are pre-defined forms that standardize how information is collected when opening a new issue. The template captures the initial context—what the user reported, where it came from, and which components are involved—so nothing is lost between intake and triage.

This is where automation kicks in. Creating the issue triggers a GitHub Action that engages GitHub Copilot, and a second Action adds the issue to a project board, providing a centralized view of current status, surfacing trends, and helping identify emerging needs.

A left-to-right flowchart where user or customer feedback enters through Discussion Board, Support Ticket, Social Media, Email, or Direct Outreach, moves to an Acknowledge and Validate step, branches at a validity decision, and either proceeds to Create Issue or loops back through Request More Details to the user.

2. GitHub Copilot analysis

With the tracking issue created, a GitHub Action workflow programmatically calls the GitHub Models API to analyze the report. We chose stored prompts over model fine-tuning so that anyone on the team can update the AI’s behavior through a pull request—no retraining pipeline, no specialized ML knowledge required.

We configured GitHub Copilot using custom instructions developed by our accessibility subject matter experts. Our prompt serves two roles: triage analysis, which classifies issues by WCAG violation, severity, and affected user group, and accessibility coaching, where GitHub Copilot acts as a subject-matter expert to help teams write and review accessible code.

These instruction files point to our accessibility policies, component library, and internal documentation that details how we interpret and apply WCAG success criteria. When our standards evolve, the team updates the markdown and instruction files via pull request—the AI’s behavior changes with the next run, not the next training cycle. For a detailed walkthrough of this approach, see our guide on optimizing GitHub Copilot custom instructions for accessibility.

The automation works in two steps. First, an Action fires on issue creation and triggers GitHub Copilot to analyze the report. GitHub Copilot populates approximately 80% of the issue’s metadata automatically—over 40 data points including issue type, user segment, original source, affected components, and enough context to understand the user’s experience. The remaining 20% requires manual input from the team member. GitHub Copilot then posts a comment on the issue containing:

  • A summary of the problem and user impact
  • Suggested WCAG success criteria for potential violations
  • Severity level (sev1 through sev4, where sev1 is critical)
  • Impacted user groups (screen reader users, keyboard users, low vision users, etc.)
  • Recommended team assignment (design, engineering, or both)
  • A checklist of low-barrier accessibility tests so the submitter can verify the issue

Then a second Action fires on that comment, parses the response, applies labels based on the severity GitHub Copilot assigned, updates the issue’s status on the project board, and assigns it to the submitter for review.

If GitHub Copilot’s analysis seems off, anyone can flag it by opening an issue describing what it got wrong and what it should have said—feeding directly into our continuous improvement process.

A left-to-right flowchart where a newly created issue triggers Action 1, which feeds the report along with custom instructions and WCAG documentation into Copilot Analysis. Copilot posts a comment with its findings, then Action 2 parses that comment and branches into four parallel outcomes: applying labels, applying metadata, adding to the project board, and assigning the submitter.

3. Submitter review

Before we act on GitHub Copilot’s recommendations, two layers of review happen—starting with the issue submitter.

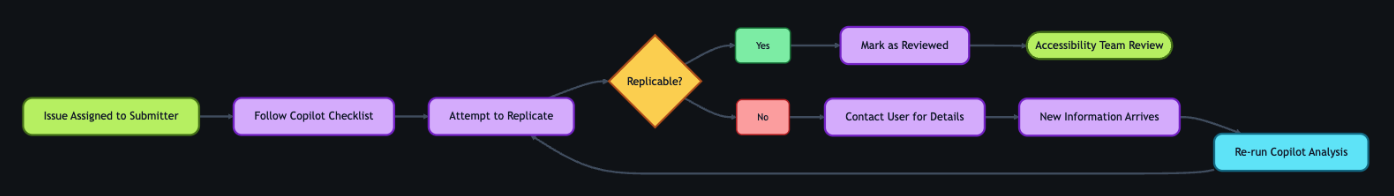
The submitter attempts to replicate the problem the user reported. The checklist GitHub Copilot provides in its comment guides our community managers, support agents, and sales reps through expert-level testing procedures—no accessibility expertise required. Each item includes plain-language explanations, step-by-step instructions, and links to tools and documentation.

Example questions include:

  • Can you navigate the page using only a keyboard? Press “Tab” to move through interactive elements. Can you reach all buttons, links, and form fields? Can you see where your focus is at all times?
  • Do images have descriptive alt text? Right-click an image and select “Inspect” to view the markup. Does the alt attribute describe the image’s purpose, or is it a generic file name?
  • Are interactive elements clearly labeled? Using a screen reader, navigate to a button or link. Is its purpose announced clearly? Alternatively, review the accessibility tree in your browser’s developer tools to inspect how elements are exposed to assistive technologies.

If the submitter can replicate the problem, they mark the issue as reviewed, which triggers the next GitHub Action. If they can’t reproduce it, they reach out to the user for more details. Once new information arrives, the submitter can re-run the GitHub Copilot analysis—either by manually triggering the Action from the Actions tab or by removing and re-adding the relevant label to kick it off automatically. AI provides the draft, but humans provide the verification.

A left-to-right flowchart where the submitter receives the issue with Copilot’s checklist, attempts to replicate the problem, and reaches a decision. If replicable, the issue is marked as reviewed and moves to the accessibility team. If not replicable, the submitter contacts the user for more details. When new information arrives, the submitter re-runs Copilot analysis, which loops back to the replication step.

4. Accessibility team review

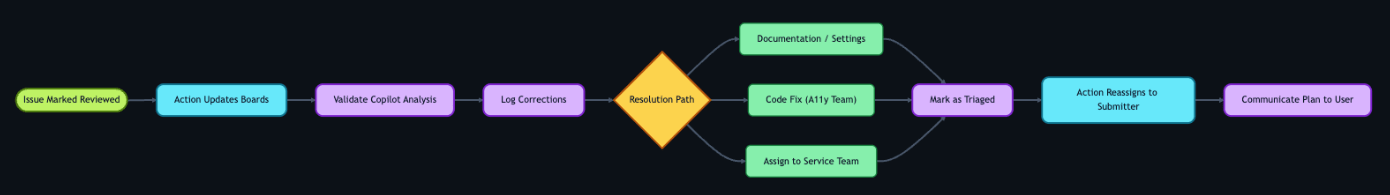
Once the submitter marks the issue as reviewed, a GitHub Action updates its status on the workflow project board and adds it to a separate accessibility first responder board. This alerts the accessibility team—engineers, designers, champions, testing vendors, and managers—that GitHub Copilot’s analysis is ready for their review.

The team validates GitHub Copilot’s analysis—checking the severity level, WCAG mapping, and category labels—and corrects anything the AI got wrong. When there’s a discrepancy, we assume the human is correct. We log these corrections and use them to refine the prompt files, improving future accuracy.

Once validated, the team determines the resolution approach:

  • Documentation or settings update: Provide the solution directly to the user.
  • Code fix by the accessibility team: Create a pull request directly.
  • Service team needed: Assign the issue to the appropriate service team and track it through resolution.

With a path forward set, the team marks the issue as triaged. An Action then reassigns it to the submitter, who communicates the plan to the user—letting them know what’s being done and what to expect.

A left-to-right flowchart where a reviewed issue triggers an Action that updates the project board and adds it to the first responder board. The accessibility team validates Copilot’s analysis, logs any corrections, then determines a resolution: provide documentation, create a code fix, or assign to a service team. All three paths converge at marking the issue as triaged, which triggers an Action that reassigns it to the submitter to communicate the plan to the user.

5. Linking to audits

As part of the review process, the team connects user and customer feedback to our formal accessibility audit system.

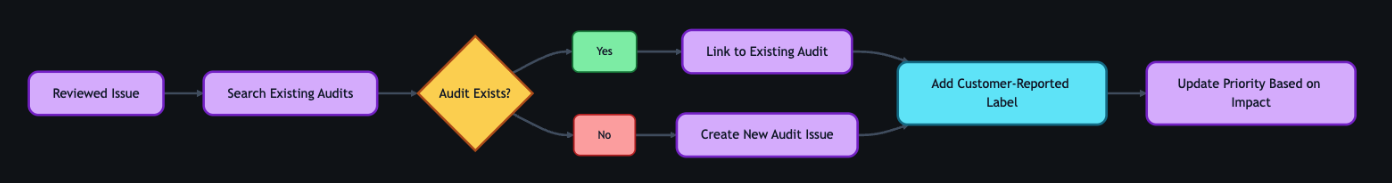
Roughly 75–80% of the time, reported issues correspond to something we already know about from internal audits. Instead of creating duplicates, we find the existing internal audit issue and add a customer-reported label. This lets us prioritize based on real-world impact—a sev2 issue might technically be less critical than a sev1, but if multiple users are reporting it, we bump up its priority.

If the feedback reveals something new, we create a new audit issue and link it to the tracking issue.

A left-to-right flowchart where the team checks whether an existing audit issue covers the reported problem. If one exists, they link it and add a customer-reported label. If not, they create a new audit issue and link it. Both paths converge at updating priority based on real-world impact.

6. Closing the loop

This is the most critical step for trust. Users who take the time to report accessibility barriers deserve to know their feedback led to action.

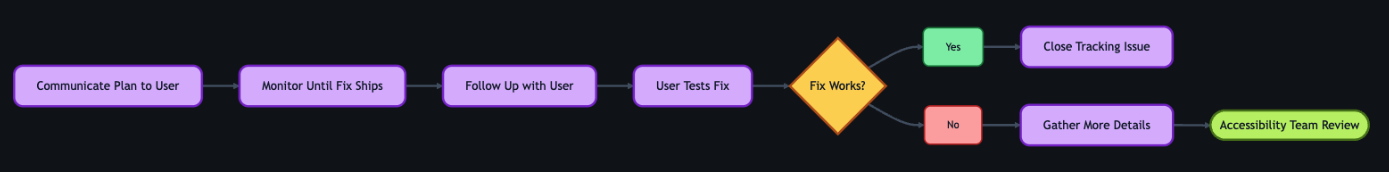
Once a resolution path is set, the submitter reaches out to the original user to let them know the plan—what’s being fixed, and what to expect. When the fix ships, the submitter follows up again and asks the user to test it. Because most issues originate from the community discussion board, we post confirmations there for everyone to see.

If the user confirms the fix works, we close the tracking issue. If the fix doesn’t fully address the problem, the submitter gathers more details and the process loops back to the accessibility team review. We don’t close issues until the user confirms the fix works for them.

A left-to-right flowchart where the submitter communicates the resolution plan to the user and monitors until the fix ships. The user is asked to test the fix. If it works, the issue is closed. If it doesn’t, the submitter gathers more details and the process loops back to the accessibility team review.

7. Continuous improvement

The workflow doesn’t end when an issue closes—it feeds back into itself.

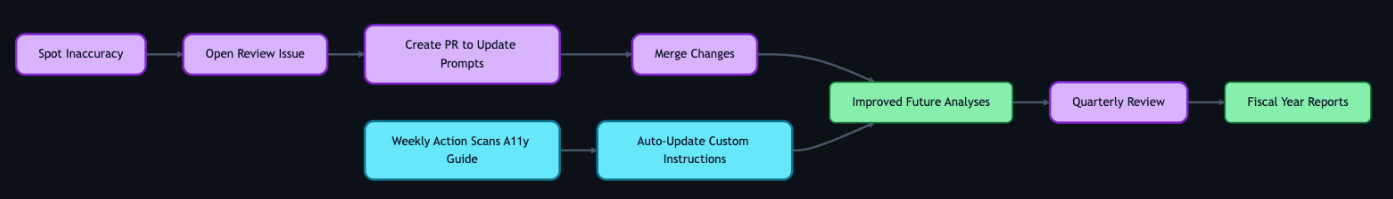
When submitters or accessibility team members spot inaccuracies in GitHub Copilot’s output, they open a new issue requesting a review of the results. Every GitHub Copilot analysis comment includes a link to create this issue at the bottom, so the feedback loop is built into the workflow itself. The team reviews the inaccuracy, and the correction becomes a pull request to the custom instruction and prompt files described earlier.

We also automate the integration of new accessibility guidance. A separate GitHub Action scans our internal accessibility guide repository weekly and incorporates changes into GitHub Copilot’s custom instructions automatically.

The goal isn’t perfection—it’s continuous improvement. Each quarter, we review accuracy metrics and refine our instructions. These reviews feed into quarterly and fiscal year reports that track resolution times, WCAG failure patterns, and feedback volume trends—giving leadership visibility into both progress and persistent gaps. The system gets smarter over time, and now we have the data to show it.

A left-to-right flowchart with two parallel loops. In the first, an inaccuracy is spotted, a review issue is opened, the team creates a pull request to update the prompt files, and the changes merge to improve future analyses. In the second, a weekly Action scans the accessibility guide repository and auto-updates Copilot's custom instructions. Both loops feed into quarterly reviews that produce fiscal year reports tracking resolution times, WCAG failure patterns, and feedback volume trends.

Impact in numbers

A year ago, nearly half of accessibility feedback sat unresolved for over 300 days. Today, that backlog isn’t just smaller—it’s gone. And the improvements don’t stop there.

  • 89% of issues now close within 90 days (up from 21%)
  • 62% reduction in average resolution time (118 days → 45 days)
  • 70% reduction in manual administrative time
  • 1,150% increase in issues resolved within 30 days (4 → 50 year-over-year)
  • 50% reduction in critical sev1 issues
  • 100% of issues closed within 60 days in our most recent quarter

We track this through automated weekly and quarterly reports generated by GitHub Actions—surfacing which WCAG criteria fail most often and how resolution times trend over time.

Beyond the numbers

A user named James emailed us to report that the GitHub Copilot CLI was inaccessible. Decorative formatting created noise for screen readers, and interactive elements were impossible to navigate.

A team member created a tracking issue. Within moments, GitHub Copilot analyzed the report—mapping James’s description to specific technical concepts, linking to internal documentation, and providing reproduction steps so the submitter could experience the product exactly as James did.

With that context, the team member realized our engineering team had already shipped accessible CLI updates earlier in the year—James simply wasn’t aware.

They replied immediately. His response? “Thanks for pointing out the –screen-reader mode, which I think will help massively.”

Because the AI workflow identified the problem correctly, we turned a frustration into a resolution in hours.

But the most rewarding result isn’t the speed—it’s the feedback from users. Not just that we responded, but that the fixes actually worked for them:

  • “Huge thanks to the team for updating the contributions graph in the high contrast theme. The addition of borders around the grid edges is a small but meaningful improvement. Keep it up!”
  • “Let’s say you want to create several labels for your GitHub-powered workflow: bug, enhancement, dependency updates… But what if you are blind? Before you had only hex codes randomly thrown at you… now it’s fixed, and those colors have meaningful English names. Well done, GitHub!”
  • “This may not be very professional but I literally just screamed! This fix has actually made my day… Before this I was getting my wife to manage the GitHub issues but now I can actually navigate them by myself! It means a lot that I can now be a bit more independent so thank you again.”

That independence is the point. Every workflow, every automation, every review—it all exists so moments like these are the expectation, not the exception.

The bigger picture

Stories like these remind us why the foundation matters. Design annotations, code scanners, accessibility champions, and testing with people with disabilities—these aren’t replaced by AI. They are what make AI-assisted workflows effective. Without that human foundation, AI is just a faster way to miss the point.

We’re still learning, and the system is still evolving. But every piece of feedback teaches us something, and that knowledge now flows continuously back to our team, our users, and the tools we build. 

If you maintain a repository—whether it’s a massive enterprise project or a weekend open-source library—you can build this kind of system today. Start small. Create an issue template for accessibility. Add a .github/copilot-instructions.md file with your team’s accessibility standards. Let AI handle the triage and formatting so your team can focus on what really matters: writing more inclusive code.

And if you hit an accessibility barrier while using GitHub, please share your feedback. It won’t disappear into a backlog. We’re listening—and now we have the system to follow through.

The post Continuous AI for accessibility: How GitHub transforms feedback into inclusion appeared first on The GitHub Blog.

From pixels to characters: The engineering behind GitHub Copilot CLI’s animated ASCII banner

Post Syndicated from Aaron Winston original https://github.blog/engineering/from-pixels-to-characters-the-engineering-behind-github-copilot-clis-animated-ascii-banner/


Most people think ASCII art is simple, and a nostalgic remnant of the early internet. But when the GitHub Copilot CLI team asked for a small entrance banner for the new command-line experience, they discovered the opposite: An ASCII animation in a real-world terminal is one of the most constrained UI engineering problems you can take on.

Part of what makes this even more interesting is the moment we’re in. Over the past year, CLIs have seen a surge of investment as AI-assisted and agentic workflows move directly into the terminal. But unlike the web—where design systems, accessibility standards, and rendering models are well-established—the CLI world is still fragmented. Terminals behave differently, have few shared standards, and offer almost no consistent accessibility guidelines. That reality shaped every engineering decision in this project.

Different terminals interpret ANSI color codes differently. Screen readers treat fast-changing characters as noise. Layout engines vary. Buffers flicker. Some users override global colors for accessibility. Others throttle redraw speed. There is no canvas, no compositor, no consistent rendering model, and no standard animation framework.

So when an animated Copilot mascot flying into the terminal appeared, it looked playful. But behind it was serious engineering work, unexpected complexity, a custom design toolchain, and a tight pairing between a designer and a long-time CLI engineer.

That complexity only became fully visible once the system was built. In the end, animating a three-second ASCII banner required over 6,000 lines of TypeScript—most of it dedicated not to visuals, but to handling terminal inconsistencies, accessibility constraints, and maintainable rendering logic.

This is the technical story of how it came together.

Why animated ASCII is a hard engineering problem

Before diving into the build process, it’s worth calling out why this problem space is more advanced than it looks.

Terminals don’t have a canvas

Unlike browsers (DOM), native apps (views), or graphics frameworks (GPU surfaces), terminals treat output as a stream of characters. There’s no native concept of:

  • Frames
  • Sprites
  • Z-index
  • Rasterized pixels
  • Animation tick rates

Because of this, every “frame” has to be manually repainted using cursor movements and redraw commands. There’s no compositor smoothing anything over behind the scenes. Everything is stdout writes + ANSI control sequences.

ANSI escape codes are inconsistent, and terminal color is its own engineering challenge

ANSI escape codes like \x1b[35m (bright magenta) or \x1b[H (cursor home) behave differently across terminals—not just in how they render, but in whether they’re supported at all. Some environments (like Windows Command Prompt or older versions of PowerShell) have limited or no ANSI support without extra configuration.

But even in terminals that do support ANSI, the hardest part isn’t the cursor movement. It’s the colors.

When you’re building a CLI, you realistically have three approaches:

  1. Use no color at all. This guarantees broad compatibility, but makes it harder to highlight meaning or guide users’ attention—especially in dense CLI output.
  2. Use richer color modes (3-bit, 4-bit, 8-bit, or truecolor) that aren’t uniformly supported or customizable. This introduces a maintenance headache: Different terminals, themes, and accessibility profiles render the same color codes differently, and users often disagree about what “good” colors look like.
  3. Use a minimal, customizable palette (usually 4-bit colors) that most terminals allow users to override in their preferences. This is the safest path, but it limits how accurately you can represent a brand palette—and it forces you to design for environments with widely varying contrast and theme choices.

For the Copilot CLI animation, this meant treating color as a semantic system, not a literal one: Instead of committing specific RGB values, the team mapped high-level “roles” (eyes, goggles, shadow, border) to ANSI colors that degrade gracefully across different terminals and accessibility settings.

Accessibility is a first-class concern

Terminals are used by developers with a wide range of visual abilities—not just blind users with screen readers, but also low-vision users, color-blind users, and anyone working in high-contrast or customized themes.

That means:

  • Rapid re-renders can create auditory clutter for screen readers
  • Color-based meaning must degrade safely, since bold, dim, or subtle hues may not be perceivable
  • Low-vision users may not see contrast differences that designers expect
  • Animations must be opt-in, not automatic
  • Clearing sequences must avoid confusing assistive technologies

This is also why the Copilot CLI animation ended up behind an opt-in flag early on—accessibility constraints shaped the architecture from the start. 

These constraints guided every decision in the Copilot CLI animation. The banner had to work when colors were overridden, when contrast was limited, and even when the animation itself wasn’t visible.

Ink (React for the terminal) helps, but it’s not an animation engine

Ink lets you build terminal interfaces using React components, but:

  • It re-renders on every state change
  • It doesn’t manage frame deltas
  • It doesn’t synchronize with terminal paint cycles
  • It doesn’t solve flicker or cursor ghosting

Which meant animation logic had to be handcrafted.

Frame-based ASCII animation has no existing workflow for designers

There are tools for ASCII art, but virtually none for:

  • Frame-by-frame editing
  • Multi-color ANSI previews
  • Exporting color roles
  • Generating Ink-ready components
  • Testing contrast and accessibility

Even existing ANSI preview tools don’t simulate how different terminals remap colors or handle cursor updates, which makes accurate design iteration almost impossible without custom tooling. So the team had to build one.

Part 1: A request that didn’t fit any workflow

Cameron Foxly (@cameronfoxly), a brand designer at GitHub with a background in animation, was asked to create a banner for the Copilot CLI.

“Normally, I’d build something in After Effects and hand off assets,” Cameron said. “But engineers didn’t have the time to manually translate animation frames into a CLI. And honestly, I wanted something more fun.”

He’d seen the static ASCII intro in Claude Code and knew Copilot deserved more personality.

The 3D Copilot mascot flying in to reveal the CLI logo felt right. But after attempting to create just one frame manually, the idea quickly ran into reality.

“It was a nightmare,” Cameron said. “If this is going to exist, I need to build my own tool.”

Part 2: Building an ASCII animation editor from scratch

Cameron opened an empty repository in VS Code, and began asking GitHub Copilot for help scaffolding an animation MVP that could:

  • Read text files as frames
  • Render them sequentially
  • Control timing
  • Clear the screen without flicker
  • Add a primitive “UI”

Within an hour, he had a working prototype that was monochrome, but functional.

Simplified early animation loop

Below is a simplified example variation of the frame loop logic Cameron prototyped:

import fs from "fs";
import readline from "readline";

/**
 * Load ASCII frames from a directory.
 */
const frames = fs
  .readdirSync("./frames")
  .filter(f => f.endsWith(".txt"))
  .map(f => fs.readFileSync(`./frames/${f}`, "utf8"));

let current = 0;

function render() {
  // Move cursor to top-left of terminal
  readline.cursorTo(process.stdout, 0, 0);

  // Clear the screen below the cursor
  readline.clearScreenDown(process.stdout);

  // Write the current frame
  process.stdout.write(frames[current]);

  // Advance to next frame
  current = (current + 1) % frames.length;
}

// 75ms = ~13fps. Higher can cause flicker in some terminals.
setInterval(render, 75);

This introduced the first major obstacle: color. The prototype worked in monochrome, but the moment color was added, inconsistencies across terminals—and accessibility constraints—became the dominant engineering problem.

Part 3: ANSI color theory and the real-world limitations

The Copilot brand palette is vibrant and high-contrast, which is great for web but exceptionally challenging for terminals.

ANSI terminals support:

  • 16-color mode (standard)
  • 256-color mode (extended)
  • Sometimes truecolor (“24-bit”) but inconsistently

Even in 256-color mode, terminals remap colors based on:

  • User themes
  • Accessibility settings
  • High-contrast modes
  • Light/dark backgrounds
  • OS-level overrides

Which means you can’t rely on exact hues. You have to design with variability in mind.

Cameron needed a way to paint characters with ANSI color roles while previewing how they look in different terminals.

He took a screenshot of the Wikipedia ANSI table, handed it to Copilot, and asked it to scaffold a palette UI for his tool.

Adding a color “brush” tool

A simplified version:

function applyColor(char, color) {
  // Minimal example: real implementation needed support for roles,
  // contrast testing, and multiple ANSI modes.
  const codes = {
    magenta: "\x1b[35m",
    cyan: "\x1b[36m",
    white: "\x1b[37m"
  };

  return `${codes[color]}${char}\x1b[0m`; // Reset after each char
}

This enabled Cameron to paint ANSI-colored ASCII like you would in Photoshop, one character at a time.

But now he had to export it into the real Copilot CLI codebase.

Part 4: Exporting to Ink (React for the terminal)

Ink is a React renderer for building CLIs using JSX components. Instead of writing to the DOM, components render to stdout.

Cameron asked Copilot to help generate an Ink component that would:

  • Accept frames
  • Render them line-by-line
  • Animate them with state updates
  • Integrate cleanly into the CLI codebase

Simplified Ink frame renderer

import React from "react";
import { Box, Text } from "ink";

/**
 * Render a single ASCII frame.
 */
export const CopilotBanner = ({ frame }) => (
  <Box flexDirection="column">
    {frame.split("\n").map((line, i) => (
      <Text key={i}>{line}</Text>
    ))}
  </Box>
);

And a minimal animation wrapper:

export const AnimatedBanner = () => {
  const [i, setI] = React.useState(0);

  React.useEffect(() => {
    const id = setInterval(() => setI(x => (x + 1) % frames.length), 75);
    return () => clearInterval(id);
  }, []);

  return <CopilotBanner frame={frames[i]} />;
};

This gave Cameron the confidence to open a pull request (his first engineering pull request in nine years at GitHub).

“Copilot filled in syntax I didn’t know,” Cameron said. “But I still made all the architectural decisions.”

Now it was time for the engineering team to turn a prototype into something production-worthy.

Part 5: Terminal animation isn’t solved technology

Andy Feller (@andyfeller), a long-time GitHub engineer behind the GitHub CLI, partnered with Cameron to bring the animation into the Copilot CLI codebase.

Unlike browsers—which share rendering engines, accessibility APIs, and standards like WCAG—terminal environments are a patchwork of behaviors inherited from decades-old hardware like the VT100. There’s no DOM, no semantic structure, and only partial agreement on capabilities across terminals. This makes even “simple” UI design problems in the terminal uniquely challenging, especially as AI-driven workflows push CLIs into daily use for more developers.

“There’s no framework for terminal animations,” Andy explained. “We had to figure out how to do this without flickering, without breaking accessibility, and across wildly different terminals.”

Andy broke the engineering challenges into four broad categories:

Challenge 1: From banner to ready without flickering

Most terminals repaint the entire viewport when new content arrives. At the same time, CLIs come with a strict usability expectation: when developers run a command, they want to get to work immediately. Any animation that flickers, blocks input, or lingers too long actively degrades the experience.

This created a core tension the team had to resolve: how to introduce a brief, animated banner without slowing startup, stealing focus, or destabilizing the terminal render loop.

In practice, this was complicated by the fact that terminals behave differently under load. Some:

  • Throttle fast writes
  • Reveal cleared frames momentarily
  • Buffer output differently
  • Repaint the cursor region inconsistently

To avoid flicker while keeping the CLI responsive across popular terminals like iTerm2, Windows Terminal, and VS Code, the team had to carefully coordinate several interdependent concerns:

  • Keeping the animation under three seconds so it never delayed user interaction
  • Separating static and non-static components to minimize unnecessary redraws
  • Initializing MCP servers, custom agents, and user setup without blocking render
  • Working within Ink’s asynchronous re-rendering model

The result was an animation treated as a non-blocking, best-effort enhancement—visible when it could be rendered safely, but never at the expense of startup performance or usability.

Challenge 2: Brand color mapping in ANSI

“ANSI color consistency simply doesn’t exist,” Andy said. 

Most modern terminals support 8-bit color, allowing CLIs to choose from 256 colors. However, how those colors are actually rendered varies widely based on terminal themes, OS settings, and user accessibility overrides. In practice, CLIs can’t rely on exact hues—or even consistent contrast—across environments.

The Copilot banner introduced an additional complexity: although it’s rendered using text characters, the block-letter Copilot logo functions as a graphical object, not readable body text. Under accessibility guidelines, non-text graphical elements have different contrast requirements than text, and they must remain perceivable without relying on fine detail or precise color matching.

To account for this, the team deliberately chose a minimal 4-bit ANSI palette—one of the few color modes most terminals allow users to customize—to ensure the animation remained legible under high-contrast themes, low-vision settings, and color overrides.

This meant the team had to:

  • Treat the Copilot wordmark as non-text graphical content with appropriate contrast requirements
  • Select ANSI color codes that approximate the Copilot palette without relying on exact hues
  • Satisfy WCAG contrast guidance for both text and non-text elements
  • Ensure the animation remained legible in light and dark terminals
  • Degrade gracefully when users override terminal colors for accessibility
  • Test color combinations across multiple terminal emulators and theme configurations

Rather than encoding brand colors directly, the animation maps semantic roles—such as borders, eyes, highlights, and text—to ANSI color slots that terminals can reinterpret safely. This allows the banner to remain recognizable without assuming control over the user’s color environment.

Dark mode version of the GitHub Copilot CLI banner.
Light mode version of the GitHub Copilot CLI banner.

Challenge 3: Making the animation maintainable

Cameron’s prototype was a great starting point for Andy to incorporate into the Copilot CLI but it wasn’t without its challenges:

  • Banner consisted of ~20 animation frames covering an 11×78 area
  • There are ~10 animation elements to stylize in any given frame
  • Needed a way to separate the text of the frame from the colors involved
  • Each frame mapped hard coded colors to row and column coordinates
  • Each frame required precise timing to display Cameron’s vision

First, the animation was broken down into distinct animation elements that could be used to create separate light and dark themes:

type AnimationElements =
    | "block_text"
    | "block_shadow"
    | "border"
    | "eyes"
    | "head"
    | "goggles"
    | "shine"
    | "stars"
    | "text";

type AnimationTheme = Record<AnimationElements, ANSIColors>;

const ANIMATION_ANSI_DARK: AnimationTheme = {
    block_text: "cyan",
    block_shadow: "white",
    border: "white",
    eyes: "greenBright",
    head: "magentaBright",
    goggles: "cyanBright",
    shine: "whiteBright",
    stars: "yellowBright",
    text: "whiteBright",
};

const ANIMATION_ANSI_LIGHT: AnimationTheme = {
    block_text: "blue",
    block_shadow: "blackBright",
    border: "blackBright",
    eyes: "green",
    head: "magenta",
    goggles: "cyan",
    shine: "whiteBright",
    stars: "yellow",
    text: "black",
};

Next, the overall animation and subsequent frames would capture content, color, duration needed to animate the banner:

interface AnimationFrame {
    title: string;
    duration: number;
    content: string;
    colors?: Record<string, AnimationElements>; // Map of "row,col" positions to animation elements
}

interface Animation {
    metadata: {
        id: string;
        name: string;
        description: string;
    };
    frames: AnimationFrame[];
}

Then, each animation frame was captured to separate frame content from stylistic and animation details, resulting in over 6,000 lines of TypeScript to safely animate three seconds of the Copilot logo across terminals with wildly different rendering and accessibility behaviors:

    const frames: AnimationFrame[] = [
        {
            title: "Frame 1",
            duration: 80,
            content: `
┌┐
││


││
└┘`,
            colors: {
                "1,0": "border",
                "1,1": "border",
                "2,0": "border",
                "2,1": "border",
                "10,0": "border",
                "10,1": "border",
                "11,0": "border",
                "11,1": "border",
            },
        },
        {
            title: "Frame 2",
            duration: 80,
            content: `
┌──     ──┐
│         │
 █▄▄▄
 ███▀█
 ███ ▐▌
 ███ ▐▌
   ▀▀█▌
   ▐ ▌
    ▐
│█▄▄▌     │
└▀▀▀    ──┘`,
            colors: {
                "1,0": "border",
                "1,1": "border",
                "1,2": "border",
                "1,8": "border",
                "1,9": "border",
                "1,10": "border",
                "2,0": "border",
                "2,10": "border",
                "3,1": "head",
                "3,2": "head",
                "3,3": "head",
                "3,4": "head",
                "4,1": "head",
                "4,2": "head",
                "4,3": "goggles",
                "4,4": "goggles",
                "4,5": "goggles",
                "5,1": "head",
                "5,2": "goggles",
                "5,3": "goggles",
                "5,5": "goggles",
                "5,6": "goggles",
                "6,1": "head",
                "6,2": "goggles",
                "6,3": "goggles",
                "6,5": "goggles",
                "6,6": "goggles",
                "7,3": "goggles",
                "7,4": "goggles",
                "7,5": "goggles",
                "7,6": "goggles",
                "8,3": "eyes",
                "8,5": "head",
                "9,4": "head",
                "10,0": "border",
                "10,1": "head",
                "10,2": "head",
                "10,3": "head",
                "10,4": "head",
                "10,10": "border",
                "11,0": "border",
                "11,1": "head",
                "11,2": "head",
                "11,3": "head",
                "11,8": "border",
                "11,9": "border",
                "11,10": "border",
            },
        },

Finally, each animation frame is rendered building segments of text based on consecutive color usage with the necessary ANSI escape codes:

           {frameContent.map((line, rowIndex) => {
                const truncatedLine = line.length > 80 ? line.substring(0, 80) : line;
                const coloredChars = Array.from(truncatedLine).map((char, colIndex) => {
                    const color = getCharacterColor(rowIndex, colIndex, currentFrame, theme, hasDarkTerminalBackground);
                    return { char, color };
                });

                // Group consecutive characters with the same color
                const segments: Array<{ text: string; color: string }> = [];
                let currentSegment = { text: "", color: coloredChars[0]?.color || theme.COPILOT };

                coloredChars.forEach(({ char, color }) => {
                    if (color === currentSegment.color) {
                        currentSegment.text += char;
                    } else {
                        if (currentSegment.text) segments.push(currentSegment);
                        currentSegment = { text: char, color };
                    }
                });
                if (currentSegment.text) segments.push(currentSegment);

                return (
                    <Text key={rowIndex} wrap="truncate">
                        {segments.map((segment, segIndex) => (
                            <Text key={segIndex} color={segment.color}>
                                {segment.text}
                            </Text>
                        ))}
                    </Text>
                );
            })}

Challenge 4: Accessibility-first design

The engineering team approached the banner with the same philosophy as the GitHub CLI’s accessibility work:

  • Respect global color overrides both in terminal and system preferences
  • After the first use, avoid animations unless explicitly enabled via the Copilot CLI configuration file
  • Minimize ANSI instructions that can confuse assistive tech

“CLI accessibility is under researched,” Andy noted. “We’ve learned a lot from users who are blind as well as users with low vision, and those lessons shaped this project.”

Because of this, the animation is opt-in and gated behind its own flag—so it’s not something developers see by default. And when developers run the CLI in –screen-reader mode, the banner is automatically skipped so no decorative characters or motion are sent to assistive technologies.

Part 6: An architecture built to scale

By the end of the refactor, the team had:

  • Frames stored as plain text
  • Animation elements
  • Themes as simple mappings
  • A runtime colorization step
  • Ink-driven timing and rendering
  • A maintainable foundation for future animations

This pattern—storing frames as plain text, layering semantic roles, and applying themes at runtime—isn’t specific to Copilot. It’s a reusable approach for anyone building terminal UIs or animations.

Part 7: What this project reveals about building for the terminal

A “simple ASCII banner” turned into:

  • A frame-based animation tool that didn’t exist
  • A custom ANSI color palette strategy
  • A new Ink component
  • A maintainable rendering architecture
  • Accessibility-first CLI design choices
  • A designer’s first engineering contribution
  • Real-world testing across diverse terminals
  • Open source contributions from the community

“The most rewarding part was stepping into open source for the first time,” Cameron said. “With Copilot, I was able to build out  my MVP ASCII animation tool into a full open source app at ascii-motion.app,. Someone fixed a typo in my README, and it made my day.”

As Andy pointed out, building accessible experiences for CLIs is still largely unexplored territory and far behind the tooling and standards available for the web.

Today, developers are already contributing to Cameron’s ASCII Motion tool, and the Copilot CLI team can ship new animations without rebuilding the system.

This is what building for the terminal demands: deep understanding of constraints, discipline around accessibility, and the willingness to invent tooling where none exists.

Use GitHub Copilot in your terminal

The GitHub Copilot CLI brings AI-assisted workflows directly into your terminal — including commands for explaining code, generating files, refactoring, testing, and navigating unfamiliar projects.

Try GitHub Copilot CLI >

The post From pixels to characters: The engineering behind GitHub Copilot CLI’s animated ASCII banner appeared first on The GitHub Blog.

Finding leaked passwords with AI: How we built Copilot secret scanning

Post Syndicated from Ashwin Mohan original https://github.blog/engineering/platform-security/finding-leaked-passwords-with-ai-how-we-built-copilot-secret-scanning/


In October 2024, we announced the general availability of Copilot secret scanning, leveraging AI to detect generic passwords in users’ codebases. This post describes how Copilot secret scanning works under the hood, the challenges we ran into when developing it, and the framework we use for testing and iteration.

What is Copilot secret scanning?

Copilot secret scanning is a feature of GitHub Secret Protection, which protects millions of repositories on GitHub by detecting hundreds of pattern types through our partner program. The precision of these detections is paramount for security teams and developers when dealing with security alerts. Historically, our detection approach has relied on regular expressions, which is an effective method for identifying secrets with strict, provider-minted formats. However, this method struggles with the nuanced and varied structures of generic passwords, often generating excessive noise for security teams and developers.

We now detect generic passwords with GitHub Copilot, using AI to analyze context—such as the usage and location of a potential secret—to limit noise and deliver relevant alerts that are critical to the health and security of your repositories.

A secret scanning alert for a password detected by Copilot secret scanning.

Getting to the point where we were confident in our password precision was a journey over many test cases, prompt iterations, and model changes. Let’s dive in to explore what we learned along the way and find out where we’re going.

The private preview highlighted a problem early on: unconventional file types and structures

At the core of Copilot secret scanning lies a request to a large language model (LLM), expressed through an LLM prompt consisting of:

  • General information about the type of vulnerability, in this case passwords.
  • The source code location and contents of the file where we believe the vulnerability may exist.
  • A strict JSON format specification for the model output, to allow for automated processing.

Our first iteration of the prompt used the few-shot prompting technique, which provides the LLM with example inputs and outputs to demonstrate how to perform the task. We wanted a resource-effective model to run the detections at scale and landed on GPT-3.5-Turbo. In parallel, we developed a basic offline evaluation framework, including manually curated test cases with both positive and negative findings, to help us validate that our approach was sound before deploying it to customers.

We deployed this first iteration to our private preview participants and immediately noticed a problem. While it worked reasonably well at identifying credentials in our offline evaluation, it would fail spectacularly in some customer repositories. The model had difficulty interpreting file types and structures not typically seen in the conventional coding languages and patterns that LLMs train on.

This experience revealed the complexity of the problem and the limiting nature of LLMs. We had to reevaluate our approach.

The road to public preview: Improving offline evaluation and prompting

In response to these initial results, we enhanced the offline evaluation framework in a few key ways. First, we added reports from private preview participants to increase the diversity of our test cases. Next, we enhanced the framework so that we could visually identify and analyze deviations resulting from model or prompt changes. This allowed us to better see the impact of customizing different steps in our prompting strategy. Finally, we leveraged the GitHub Code Security team’s evaluation processes to create a data collection pipeline, and used GPT-4 to create our own test cases based on learnings from existing secret scanning alerts in open source repositories.

This improved offline evaluation and gave us the breadth needed to measure both precision and recall. Precision is the ability to find secrets more accurately, with concerns to the false positive rate, while recall is the ability to find secrets more reliably, with concerns to the false negative rate.

A diagram illustrating the difference between precision and recall.
Walber, CC BY-SA 4.0, via Wikimedia Commons

From here, we ran a series of experiments to evaluate detection quality:

  • What if we tried a different model?
  • What if we ran the prompt multiple times and somehow combined the responses?
  • What if we ran two different prompts on two different models in sequence?
  • How do we better handle the nondeterministic nature of LLM responses?

More specifically, we started experimenting with a few different mechanisms to improve our detection with the LLM.

We tried voting (asking the model the same question many times), which allowed for more deterministic responses but had no material impact on our precision.

We also tried using a larger model (GPT-4) trained on a larger set of parameters as a confirming scanner, to validate the accuracy of candidates found by GPT-3.5-Turbo. This helped improve precision without reducing our recall, but was also more resource intensive.

We also tried a few different prompting strategies, such as Fill-in-the-Middle, Zero-Shot, and Chain-of-Thought. We ended up collaborating with our colleagues at Microsoft and used their MetaReflection technique, a novel offline reinforcement learning technique that allows experiential learnings from past trials to come up with a hybrid Chain of Thought (CoT) and few-shot prompt that improves precision with a small penalty in recall.

We ultimately ended up using a combination of all these techniques and moved Copilot secret scanning into public preview, opening it widely to all GitHub Secret Protection customers. This brings us to our next hurdle: scale.

Scaling out capacity for a public preview

Secret scanning not only scans incoming Git pushes, but also your entire Git history on all branches. With each new customer, the necessary resources increase linearly. Rather than simply expanding LLM capacity, we focused on striking the most effective balance between value and cost to ensure optimal performance and efficiency. Before tackling how we managed the resources, we tried to find ways to reduce resource usage itself by:

  • Identifying and excluding a class of changes from scanning (such as media files or language files that contain “test,” “mock,” or “spec” in the filepath), because we expected they would never contain credentials or they would be incomprehensible to the model.
  • Experimenting with newer models, such as GPT-4-Turbo and GPT-4o-mini, that were expected to be less resource intensive without compromising on performance and latency.
  • Experimenting with different context windows to find one that reduced resources without significantly increasing latency for the LLM to respond to our queries.
  • Making improvements to how we tokenize the content we want to scan, including retaining some memory of previous tokenizations while processing new parts of a file.

While some of these efforts proved fruitful, such as limiting the content we scanned, other efforts were less effective. For example, breaking down content into smaller pieces didn’t have much of an impact, while using a more powerful model did.

Ultimately, the most impactful change came from creating a workload-aware request management system that allowed us to maximize and equitably share LLM capacity against the variety of different workloads we run during scans.

In building the system, we noticed a fundamental problem that needed addressing in our capacity management: assigning specific rate limits to individual workloads (such as scanning incoming Git commits or scanning the full history) was suboptimal. As each workload was tied to specific traffic patterns—Git commits, for example, tend to correlate with working hours, while full history scanning correlates with discrete events like a security manager or administrator enabling the feature on a new organization—it was easy to land in a situation where an individual workload could run into rate limits within its operational context, leaving additional resources available elsewhere unused.

We drew significant inspiration from existing solutions in this space, such as Doorman, GitHub’s own Freno, and various other weighted, fair-priority, queue-related algorithms. We came up with an algorithm that allows us to set a range of limits for each workload, preventing the workload from completely overwhelming the LLM, while allowing it to tap into resources from other workloads going unused at the moment. This strategy was so effective at maximizing utilization that we ended up using it within Copilot Autofix and security campaigns as well.

Mirror testing our way to general availability

Achieving confidence in detection quality was crucial for moving Copilot secret scanning to general availability. We implemented a mirror testing framework that ran our prompt and filtering changes against a subset of repositories that participated in our public preview. Rescanning these repositories with our latest improvements allowed us to assess the change in real alert volumes and false positive resolutions, without impacting users.

We found a huge drop in detections and false positives with very few missing real passwords. In some cases, we saw a 94% reduction in false positives across organizations! This before-and-after comparison indicated that all the different changes we made during private and public preview led to increased precision without sacrificing recall, and that we were ready to provide a reliable and efficient detection mechanism to all GitHub Secret Protection customers.

Lessons for the future

Copilot secret scanning is now detecting passwords on nearly 35% of all GitHub Secret Protection repositories. We’re continuing to monitor performance and apply lessons learned as we leverage the tooling we created along the way:

  • A focus on precision: Security and development teams need accurate and actionable alerts without the noise—this is always our primary goal.
  • Including diverse test cases: We continue to incorporate examples based on learnings from customer feedback into our test bed as we refine our detection capabilities.
  • Effective resource management: We always need to balance scalability with performance.
  • Collaborative innovation: Partnering with other GitHub and Microsoft teams helps us push the boundaries of what Copilot can achieve.

These learnings are also shared across Copilot Autofix, which continues to expand coverage for code scanning alerts and helps development teams remediate code scanning alerts quickly.

Since our general availability launch, enablement for Copilot secret scanning has been included in security configurations, allowing you to control which repositories are detecting secrets across your organizations or enterprise. We’re dedicated to continuous improvement through ongoing monitoring, mirror testing, and approach refinement based on customer feedback and detection trends. Copilot secret scanning serves as a critical component for robust application security and will evolve to meet the dynamic needs of our users.

Copilot secret scanning is a feature of GitHub Secret Protection, which offers enterprise-ready solutions for preventing accidental secret exposure in your repositories. GitHub Secret Protection is available to purchase starting April 1, 2025.

The post Finding leaked passwords with AI: How we built Copilot secret scanning appeared first on The GitHub Blog.

How to debug code with GitHub Copilot

Post Syndicated from Jeimy Ruiz original https://github.blog/ai-and-ml/github-copilot/how-to-debug-code-with-github-copilot/


Debugging is an essential part of a developer’s workflow—but it’s also one of the most time consuming. What if AI could streamline the process, helping you analyze, fix, and document code faster? Enter GitHub Copilot, your AI-powered coding assistant.

GitHub Copilot isn’t just for writing code—it’s also a powerful tool for debugging. Whether you’re troubleshooting in your IDE, using Copilot Chat’s slash commands like /fix, or reviewing pull requests (PR) on github.com, GitHub Copilot offers flexible, intelligent solutions to speed up your debugging process. And with the free version of GitHub Copilot, available to all personal GitHub accounts, you can start exploring these features today.

In this guide, we’ll explore how to debug code with GitHub Copilot, where to use it in your workflow, and best practices to get the most out of its capabilities. Whether you’re new to GitHub Copilot or looking to deepen your skills, this guide has something for you.

Debugging code with GitHub Copilot: surfaces and workflows

Debugging code with GitHub Copilot can help you tackle issues faster while enhancing your understanding of the codebase. Whether you’re fixing syntax errors, refactoring inefficient code, or troubleshooting unexpected behavior, GitHub Copilot can provide valuable insights in your debugging journey.

So, how exactly does this work? “GitHub Copilot is recognizing patterns and suggesting solutions based on what it has learned,” says Christopher Harrison, Senior Developer Advocate. “Once you’ve identified the problem area, you can turn to GitHub Copilot and ask, ‘I’m giving this input but getting this output—what’s wrong?’ That’s where GitHub Copilot really shines.”

Let’s explore how GitHub Copilot can help you debug your code across different surfaces, from your IDE to github.com and even pull requests.

1. In Copilot Chat

Copilot Chat acts as an interactive AI assistant, helping you debug issues with natural language queries. And with Copilot Free, you get 50 chat messages per month. With Copilot Chat, you can:

  • Get real-time explanations: Ask “Why is this function throwing an error?” and Copilot Chat will analyze the code and provide insights.
  • Use slash commands for debugging: Try /fix to generate a potential solution or /explain for a step-by-step breakdown of a complex function. (More on this later!)
  • Refactor code for efficiency: If your implementation is messy or inefficient, Copilot Chat can suggest cleaner alternatives. Christopher explains, “Refactoring improves the readability of code, making it easier for both developers and GitHub Copilot to understand. And if code is easier to understand, it’s easier to debug and spot problems.”
  • Walk through errors interactively: Describe your issue in chat and get tailored guidance without ever having to leave your IDE.

2. In your IDE

When working in popular IDEs like VS Code or JetBrains, GitHub Copilot offers real-time suggestions as you type. It helps by:

  • Flagging issues: For example, if you declare a variable but forget to initialize it, GitHub Copilot can suggest a correction.
  • Code fixes: Encounter a syntax error? GitHub Copilot can suggest a fix in seconds, ensuring your code stays error-free.
  • Contextual assistance: By analyzing your workspace, GitHub Copilot provides solutions tailored to your codebase and project structure.

3. On github.com

GitHub Copilot extends beyond your IDE, offering debugging assistance directly on github.com via Copilot Chat, particularly in repositories and discussions. With this feature, you can:

  • Troubleshoot code in repositories: Open a file, highlight a problematic section, and use Copilot Chat to analyze it.
  • Generate test cases: If you’re unsure how to verify a function, GitHub Copilot can suggest test cases based on existing code.
  • Understand unfamiliar code: Reviewing an open-source project or a teammate’s PR? Ask GitHub Copilot to summarize a function or explain its logic.

4. For pull request assistance

GitHub Copilot can also streamline debugging within PRs, ensuring code quality before merging.

  • Suggest improvements in PR comments: GitHub Copilot can review PRs and propose fixes directly in the conversation.
  • Generate PR summaries: Struggling to describe your changes? Greg Larkin, Senior Service Delivery Engineer, says, “I use GitHub Copilot in the PR creation process to generate a summary of the changes in my feature branch compared to the branch I’m merging into. That can be really helpful when I’m struggling to figure out a good description, so that other people understand what I did.”
  • Explain diffs: Not sure why a change was made? Ask GitHub Copilot to summarize what’s different between commits.
  • Catch edge cases before merging: Use /analyze to identify potential issues and /tests to generate missing test cases.
  • Refactor on the fly: If a PR contains redundant or inefficient code, GitHub Copilot can suggest optimized alternatives.

By integrating Copilot into your PR workflow, you can speed up code reviews while maintaining high-quality standards. Just be sure to pair it with peer expertise for the best results.

5 slash commands in GitHub Copilot for debugging code

Slash commands turn GitHub Copilot into an on-demand debugging assistant, helping you solve issues faster, get more insights, and improve your code quality. Here are some of the most useful slash commands for debugging:

1. Use /help to get guidance on using GitHub Copilot effectively

The /help slash command provides guidance on how to interact with GitHub Copilot effectively, offering tips on structuring prompts, using slash commands, and maximizing GitHub Copilot’s capabilities.

  • How it works: Type /help in Copilot Chat to receive suggestions on your current task, whether it’s debugging, explaining code, or generating test cases.
  • Example: Need a refresher on what GitHub Copilot can do? Use /help to access a quick guide to slash commands like /fix and /explain.

2. Use /fix to suggest and apply fixes

The /fix command is a go-to tool for resolving code issues by allowing you to highlight a block of problematic code or describe an error.

  • How it works: Select the code causing issues, type /fix, and let Copilot Chat generate suggestions.
  • Example: If you have a broken API call, use /fix to get a corrected version with appropriate headers or parameters.

3. Use /explain to understand code and errors

The /explain command breaks down complex code or cryptic error messages into simpler, more digestible terms.

  • How it works: Highlight the code or error message you want clarified, type /explain, and Copilot Chat will provide an explanation. It will explain the function’s purpose, how it processes the data, potential edge cases, and any possible bugs or issues.
  • Example: Encounter a “NullPointerException”? Use /explain to understand why it occurred and how to prevent it.

4. Use /tests to generate tests

Testing is key to identifying bugs, and the /tests command helps by generating test cases based on your code.

  • How it works: Use /tests on a function or snippet, and Copilot Chat will generate relevant test cases.
  • Example: Apply /tests to a sorting function, and Copilot Chat might generate unit tests for edge cases like empty arrays or null inputs.

5. Use /doc to generate or improve documentation

There are long-term benefits to having good text documentation—for developers and GitHub Copilot, which can draw context from it—because it makes your codebase that much more searchable. By using the /doc command with Copilot Free, you can even ask GitHub Copilot to write a summary of specific code blocks within your IDE.

The /doc command helps you create or refine documentation for your code, which is critical when debugging or collaborating with others. Clear documentation provides context for troubleshooting, speeds up issue resolution, and helps fellow developers understand your code faster.

  • How it works: Highlight a function, class, or file, type /doc and right-click to see the context menu, and Copilot Chat will generate comprehensive comments or documentation.
  • Example: Apply /doc to a function, and Copilot Chat will generate inline comments detailing its purpose, parameters, and expected output.

By mastering these commands, you can streamline your debugging workflow and resolve issues faster without switching between tools or wasting time on manual tasks.

Best practices for debugging code with GitHub Copilot

Provide clear context for better results

Providing the right context helps GitHub Copilot generate even more relevant debugging suggestions. As Christopher explains, “The better that Copilot is able to understand what you’re trying to do and how you’re trying to do it, the better the responses are that it’s able to give to you.”

Since GitHub Copilot analyzes your code within the surrounding scope, ensure your files are well structured and that relevant dependencies are included. If you’re using Copilot Chat, reference specific functions, error messages, or logs to get precise answers instead of generic suggestions.

💡 Pro tip: Working across multiple files? Use the @workspace command to point GitHub Copilot in the right direction and give it more context for your prompt and intended goal.

Ask, refine, and optimize in real time

Instead of treating GitHub Copilot as a one-and-done solution, refine its suggestions by engaging in a back-and-forth process. Greg says, “I find it useful to ask GitHub Copilot for three or four different options on how to fix a problem or to analyze for performance. The more detail you provide about what you’re after—whether it’s speed, memory efficiency, or another constraint—the better the result.”

This iterative approach can help you explore alternative solutions you might not have considered, leading to more robust and efficient code.

Master the art of specific prompts

The more specific your prompt, the better GitHub Copilot’s response. Instead of asking “What’s wrong with this function?” try “Why is this function returning undefined when the input is valid?” GitHub Copilot performs best when given clear, detailed queries—this applies whether you’re requesting a fix, asking for an explanation, or looking for test cases to verify your changes.

By crafting precise prompts and testing edge cases, you can use GitHub Copilot to surface potential issues before they become production problems.

Try a structured approach with progressive debugging

Next, try a step-by-step approach to your debugging process! Instead of immediately applying fixes, use GitHub Copilot’s commands to first understand the issue, analyze potential causes, and then implement a solution. This structured workflow—known as progressive debugging—helps you gain deeper insights into your code while ensuring that fixes align with the root cause of the problem.

For example:

  1. Start with the slash command /explain on a problematic function to understand the issue.
  2. Use the slash command /startDebugging to help with configuring interactive debugging.
  3. Finally, apply the slash command /fix to generate possible corrections.

📌 Use case: If a function in your React app isn’t rendering as expected, start by running /explain on the relevant JSX or state logic, then use /debug to identify mismanaged props, and finally, apply /fix for a corrected implementation.

Combine commands for a smarter workflow

Some issues require multiple levels of debugging and refinement. By combining commands, you can move from diagnosis to resolution even faster.

For example:

  • Use /explain + /fix to understand and resolve issues quickly.
  • Apply /fixTestFailure + /tests to find failing tests and generate new ones.

📌 Use case:

  • Fixing a broken function: Run the slash command /explain to understand why it fails, then use the slash command /fix to generate a corrected version.
  • Improving test coverage: Use the slash command /fixTestFailure to identify and fix failing tests, then use the slash command /tests to generate additional unit tests for the highlighted code.

Remember, slash commands are most effective when they’re used in the appropriate context, combined with clear descriptions of the problem, are part of a systematic debugging approach, and followed up with verification and testing.

Better together: AI tools with a developer in the pilot’s chair

GitHub Copilot is a powerful tool that enhances your workflow, but it doesn’t replace the need for human insight, critical thinking, and collaboration. As Greg points out, “GitHub Copilot can essentially act as another reviewer, analyzing changes and providing comments. Even so, it doesn’t replace human oversight. Having multiple perspectives on your code is crucial, as different reviewers will spot issues that others might miss.”

By combining GitHub Copilot’s suggestions with human expertise and rigorous testing, you can debug more efficiently while maintaining high-quality, reliable code.

Ready to try the free version of GitHub Copilot?
Start using GitHub Copilot today >

You can keep the learning going with these resources:
* Debug your app with GitHub Copilot in Visual Studio
* Example prompts for GitHub Copilot Chat
* GitHub Copilot and VS Code tutorials

The post How to debug code with GitHub Copilot appeared first on The GitHub Blog.

Unlocking the power of unstructured data with RAG

Post Syndicated from Nicole Choi original https://github.blog/2024-06-13-unlocking-the-power-of-unstructured-data-with-rag/


Whether they’re building a new product or improving a process or feature, developers and IT leaders need data and insights to make informed decisions.

When it comes to software development, this data exists in two ways: unstructured and structured. While structured data follows a specific and predefined format, unstructured data—like email, an audio or visual file, code comment, or commit message—doesn’t. This makes unstructured data hard to organize and interpret, which means teams can miss out on potentially valuable insights.

To make the most of their unstructured data, development teams are turning to retrieval-augmented generation, or RAG, a method for customizing large language models (LLMs). They can use RAG to keep LLMs up to date with organizational knowledge and the latest information available on the web. They can also use RAG and LLMs to surface and extract insights from unstructured data.

GitHub data scientists, Pam Moriarty and Jessica Guo, explain unstructured data’s unique value in software development, and how developers and organizations can use RAG to create greater efficiency and value in the development process.

Unstructured data in software development

When it comes to software development, unstructured data includes source code and the context surrounding it, as these sources of information don’t follow a predefined format.

Here are some examples of unstructured data on GitHub:

  • README files describe in text the purpose behind project source code, and include instructions for source code use, how to contribute, and other details that developers decide is important to include. While they’re usually written in Markdown, README files don’t follow a predefined structure.
  • Code files are more orderly than README files in that they follow the syntax of a programming language. But not all code files have the exact same fields nor are they all written in the same format. Additionally, some parts of the file, like coding logic and variable names, are decided by individual developers.
  • Package documentation explains how the software works and how to use it. Documentation, written in natural language, can include installation instructions, troubleshooting tips, a description of the package’s API, and a list of any dependencies required to use the package. It can also include code snippets that highlight the package’s features.
  • Code comments explain the function behind certain code blocks in a code file. They’re text comments written in natural language and make the source code easier to understand by other developers.
  • Wiki pages, while not limited to unstructured data, can contain helpful text documentation about installation instructions, API references, and other information.
  • Commit messages describe in natural language text the changes a developer made to a codebase and why.
  • Issue and pull request descriptions are written in natural language and in a text field. They can contain any kind of information a developer chooses to include about a bug, feature request, or general task in a project.
  • Discussions contain a wealth and variety of information, from developer and end- user feedback to open-ended conversations about a topic. As long as a repository enables discussions, anyone with a GitHub account can start a discussion.
  • Review comments are where developers can discuss changes before they’re merged into a codebase. Consequently, they contain information in natural language about code quality, context behind certain decisions, and concerns about potential bugs.

The value of unstructured data

The same features that make unstructured data valuable also make it hard to analyze.

Unstructured data lacks inherent organization, as it often consists of free-form text, images, or multimedia content.

“Without clear boundaries or predefined formats, extracting meaningful information from unstructured data becomes very challenging,” Guo says.

But LLMs can help to identify complex patterns in unstructured data—especially text. Though not all unstructured data is text, a lot of text is unstructured. And LLMs can help you to analyze it.

“When dealing with ambiguous, semi-structured or unstructured data, LLMs dramatically excel at identifying patterns, sentiments, entities, and topics within text data and uncover valuable insights that might otherwise remain hidden,” Guo explains.

Here are a few reasons why developers and IT leaders might consider using RAG-powered LLMs to leverage unstructured data:

  • Surface organizational best practices and establish consistency. Through RAG, an LLM can receive a prompt with additional context pulled from an organization’s repositories and documents. So, instead of sifting through and piece-mealing documents, developers can quickly receive answers from an LLM that align with their organization’s knowledge and best practices.
  • Accelerate and deepen understanding of an existing codebase—including its conventions, functions, common issues, and bugs. Understanding and familiarizing yourself with code written by another developer is a persisting challenge for several reasons, including but not limited to: code complexity, use of different coding styles, a lack of documentation, use of legacy code or deprecated libraries and APIs, and the buildup of technical debt from quick fixes and workarounds.

RAG can help to mediate these pain points by enabling developers to ask and receive answers in natural language about a specific codebase. It can also guide developers to relevant documentation or existing solutions.

Accelerated and deepened understanding of a codebase enables junior developers to contribute their first pull request with less onboarding time and senior developers to mitigate live site incidents, even when they’re unfamiliar with the service that’s failing. It also means that legacy code suffering from “code rot” and natural aging can be more quickly modernized and easily maintained.

Unstructured data doesn’t just help to improve development processes. It can also improve product decisions by surfacing user pain points.

Moriarty says, “Structured data might show a user’s decision to upgrade or renew a subscription, or how frequently they use a product or not. While those decisions represent the user’s attitude and feelings toward the product, it’s not a complete representation. Unstructured data allows for more nuanced and qualitative feedback, making for a more complete picture.”

A lot of information and feedback is shared during informal discussions, whether those discussions happen on a call, over email, on social platforms, or in an instant message. From these discussions, decision makers and builders can find helpful feedback to improve a service or product, and understand general public and user sentiment.

What about structured data?

Contrary to unstructured data, structured data—like relational databases, Protobuf files, and configuration files—follows a specific and predefined format.

We’re not saying unstructured data is more valuable than structured. But the processes for analyzing structured data are more straightforward: you can use SQL functions to modify the data and traditional statistical methods to understand the relationship between different variables.

That’s not to say AI isn’t used for structured data analysis. “There’s a reason that machine learning, given its predictive power, is and continues to be widespread across industries that use data,” according to Moriarty.

However, “Structured data is often numeric, and numbers are simply easier to analyze for patterns than words are,” Moriarty says. Not to mention that methods for analyzing structured data have been around longer** **than those for analyzing unstructured data: “A longer history with more focus just means there are more established approaches, and more people are familiar with it,” she explains.

That’s why the demand to enhance structured data might seem less urgent, according to Guo. “The potential for transformative impact is significantly greater when applied to unstructured data,” she says.

How does RAG extract value from unstructured data?

With RAG, an LLM can use data sources beyond its training data to generate an output.

RAG is a prompting method that uses retrieval—a process for searching for and accessing information—to add more context to a prompt that generates an LLM response.

This method is designed to improve the quality and relevance of an LLM’s outputs. Additional data sources include a vector database, traditional database, or search engine. So, developers who use an enterprise AI tool equipped with RAG can receive AI outputs customized to their organization’s best practices and knowledge, and proprietary data.

We break down these data sources in our RAG explainer, but here’s a quick summary:

  • Vector databases. While you code in your IDE, algorithms create embeddings for your code snippets, which are stored in a vector database. An AI coding tool can search that database to find snippets from across your codebase that are similar to the code you’re currently writing and generate a suggestion.

And when you’re engaging with GitHub Copilot Chat on GitHub.com or in the IDE, your query or code is transformed into an embedding. Our retrieval service then fetches relevant embeddings from the vector database for the repository you’ve indexed. These embeddings are turned back into text and code when they’re added to the prompt as additional context for the LLM. This entire process leverages unstructured data, even though the retrieval system uses embeddings internally.

  • General text search. When developers engage with GitHub Copilot Chat under a GitHub Copilot Enterprise plan, they can index repositories—specifically code and documentation. So, when a developer on GitHub.com or in the IDE asks GitHub Copilot Chat a question about an indexed repository, the AI coding tool can retrieve data from all of those indexed, unstructured data sources. And on GitHub.com, GitHub Copilot Chat can tap into a collection of unstructured data in Markdown files from across repositories, which we call knowledge bases.

Learn about GitHub Copilot Enterprise features >

But wait, why is Markdown considered unstructured data? Though you can use Markdown to format a file, the file itself can contain essentially any kind of data. Think about it this way: how would you put the contents of a Markdown file in a table?

  • External or internal search engine. The retrieval method searches and pulls information from a wide range of sources from the public web or your internal platforms and websites. That information is used for RAG, which means the AI model now has data from additional files—like text, image, video, and audio—to answer your questions.

Retrieval also taps into internal search engines. So, if a developer wants to ask a question about a specific repository, they can index the repository and then send their question to GitHub Copilot Chat on GitHub.com. Retrieval uses our internal search engine to find relevant code or text from the indexed files, which are then used by RAG to prompt the LLM for a contextually relevant response.

Stay smart: LLMs can do things they weren’t trained to do, so it’s important to always evaluate and verify their outputs.

Use RAG to unlock insights from unstructured data

As developers improve their productivity and write more code with AI tools like GitHub Copilot, there’ll be even more unstructured data. Not just in the code itself, but also the information used to build, contextualize, maintain, and improve that code.

That means even more data containing rich insights that organizations can surface and leverage, or let sink and disappear.

Developers and IT leaders can use RAG as a tool to help improve their productivity, produce high-quality and consistent code at greater speed, preserve and share information, and increase their understanding of existing codebases, which can impact reduced onboarding time.

With a RAG-powered AI tool, developers and IT leaders can quickly discover, analyze, and evaluate a wealth of unstructured data—simply by asking a question.

A RAG reading list 📚

The post Unlocking the power of unstructured data with RAG appeared first on The GitHub Blog.

4 ways GitHub engineers use GitHub Copilot

Post Syndicated from Holger Staudacher original https://github.blog/2024-04-09-4-ways-github-engineers-use-github-copilot/

Just recently, I was coding a new feature for GitHub Copilot Chat. My task was to enable the chat to recognize a user’s project dependencies, allowing it to provide magical answers when the user poses a question. While I could have easily listed the project dependencies and considered the task complete, I knew that to extract top-notch responses from these large language models, I needed to be careful to not overload the prompt to avoid confusing the model by providing too much context. This meant pre-processing the dependency list and selecting the most relevant ones to include in the chat prompt.

Creating machine-processable formats for the most prominent frameworks across various programming languages would have consumed days. It was during this time that I experienced one of those “Copilot moments.”

I simply queried the chat in my IDE:

Look at the data structure I have selected and create at least 10 examples that conform to the data structure. The data should cover the most prominent frameworks for the Go programming language.

Voilà, there it was my initial batch of machine-processable dependencies. Just 30 minutes later, I had amassed a comprehensive collection of significant dependencies for nearly all supported languages, complete with parameterized unit tests. Completing a task that would likely have taken days without GitHub Copilot, in just 30 minutes, was truly remarkable.

This led me to ponder: what other “Copilot moments” might my colleagues here at GitHub have experienced? Thus, here are a few ways we use GitHub Copilot at GitHub.

1. Semi-automating repetitive tasks

Semi-automating repetitive tasks is a topic that resonates with a colleague of mine from another team. He mentions that they are tasked with developing and maintaining several live services, many of which utilize protocol buffers for data communication. During maintenance, they often encounter a situation where they need to increment ID numbers in the protobuf definitions, as illustrated in the code snippet below:

protobuf

google.protobuf.StringValue fetcher = 130

  [(opts.cts_opt)={src:"Properties" key:"fetcher"}];

google.protobuf.StringValue proxy_enabled = 131

  [(opts.cts_opt)={src:"Properties" key:"proxy_enabled"}];

google.protobuf.StringValue proxy_auth = 132

  [(opts.cts_opt)={src:"Properties" key:"proxy_auth"}];

He particularly appreciates having GitHub Copilot completions in the editor for these tasks. It serves as a significant time saver, eliminating the need to manually generate ID numbers. Instead, one can simply tab through the completion suggestions until the task is complete.

2. Avoid getting side tracked

Here’s another intriguing use case I heard about from a colleague. He needed to devise a regular expression to capture a Markdown code block and extract the language identifier. Fully immersed in his work, he preferred not to interrupt his flow by switching to chat, even though it could have provided a solution. Instead, he employed a creative approach by formalizing his task in a code comment:

// The string above contains a code block with a language identifier.
// Create a regexp that matches the code block and captures the language 
identifier.
// Use tagged capture groups for the language and the code. 

This prompted GitHub Copilot to generate the regular expression as the subsequent statement in his editor:

const re = /```(?<lang>\w+)(?<code>[\s\S]+?)```/;

With the comment deleted, the task was swiftly accomplished!

Screenshot of GitHub engineer prompting GitHub Copilot, and GItHub Copilot returning a useful response

During a pleasant coffee chat, one of our support engineers shared an incident she experienced with a colleague last week. It was a Friday afternoon, and they were attempting to troubleshoot an issue for a specific customer. Eventually, they pinpointed the solution by creating various notes in VSCode. At GitHub, we prioritize remote collaboration. Thus, merely resolving the task wasn’t sufficient; it was also essential to inform our colleagues about the process to ensure the best possible experience for future customer requests. Consequently, even after completing this exhaustive task, they needed to document how they arrived at the solution.

She initiated GitHub Copilot Chat and simply typed something along the lines of, “Organize my notes, structure them, and compile the data in the editor into Markdown tables.” Within seconds, the task was completed, allowing them to commence their well-deserved weekend.

4. Exploring and learning

Enhancing and acquiring new skills are integral aspects of every engineer’s journey. John Berryman, a colleague of mine, undertook the challenge of leveraging GitHub Copilot to tackle a non-trivial coding task in a completely unfamiliar programming language. His goal was to delve into Rust, so on a Sunday, he embarked on this endeavor with the assistance of GitHub Copilot Chat. The task he set out to accomplish was to develop a program capable of converting any numerical input into its written English equivalent. While initially seeming straightforward, this task presented various complexities such as handling teen numbers, naming conventions for tens, placement of “and” in the output, and more.

Twenty-three minutes and nine seconds later, he successfully produced a functional version written in Rust, despite having no prior experience with the language. Notably, he documented his entire process, recording himself throughout the endeavor.

Berryman uses an older, experimental version of GitHub Copilot to write a program in Rust.

Your very own GitHub Copilot moment

I found it incredibly enlightening to discover how my fellow Hubbers utilize GitHub Copilot, and their innovative approaches inspired me to incorporate some of their ideas into my daily workflows. If you’re eager to explore GitHub Copilot firsthand, getting started is a breeze. Simply install it into your preferred editor and ask away.

The post 4 ways GitHub engineers use GitHub Copilot appeared first on The GitHub Blog.

Using GitHub Copilot in your IDE: Tips, tricks, and best practices

Post Syndicated from Kedasha Kerr original https://github.blog/2024-03-25-how-to-use-github-copilot-in-your-ide-tips-tricks-and-best-practices/


AI has become an integral part of my workflow these days, and with the assistance of GitHub Copilot, I move a lot faster when I’m building a project. Having used AI tools to increase my productivity over the past year, I’ve realized that similar to learning how to use a new framework or library, we can enhance our efficiency with AI tools by learning how to best use them.

In this blog post, I’ll share some of the daily things I do to get the most out of GitHub Copilot. I hope these tips will help you become a more efficient and productive user of the AI assistant.

Need a refresher on how to use GitHub Copilot?Since GitHub Copilot continues to evolve in the IDE, CLI, and across GitHub.com, we put together a full guide on using GitHub Copilot with prompt tips and tricks. Get the guide >

Want to learn how best to leverage it in the IDE? Keep on reading. ⤵

Beyond code completion

To make full use of the power of GitHub Copilot, it’s important to understand its capabilities. GitHub Copilot is developing rapidly, and new features are being added all the time. It’s no longer just a code completion tool in your editor—it now includes a chat interface that you can use in your IDE, a command line tool via a GitHub CLI extension, a summary tool in your pull requests, a helper tool in your terminals, and much, much more.

In a recent blog post, I’ve listed some of the ways you didn’t know you could use GitHub Copilot. This will give you a great overview of how much the AI assistant can currently do.

But beyond interacting with GitHub Copilot, how do you help it give you better answers? Well, the answer to that needs a bit more context.

Context, context, context

If you understand Large Language Models ( LLMs), you will know that they are designed to make predictions based on the context provided. This means, the more contextually rich our input or prompt is, the better the prediction or output will be.

As such, learning to provide as much context as possible is key when interacting with GitHub Copilot, especially with the code completion feature. Unlike ChatGPT where you need to provide all the data to the model in the prompt window, by installing GitHub Copilot in your editor, the assistant is able to infer context from the code you’re working on. It then uses that context to provide code suggestions.

We already know this, but what else can we do to give it additional context?

I want to share a few essential tips with you to provide GitHub Copilot with more context in your editor to get the most relevant and useful code out of it:

1. Open your relevant files

Having your files open provides GitHub Copilot with context. When you have additional files open, it will help to inform the suggestion that is returned. Remember, if a file is closed, GitHub Copilot cannot see the file’s content in your editor, which means it cannot get the context from those closed files.

GitHub Copilot looks at the current open files in your editor to analyze the context, create a prompt that gets sent to the server, and return an appropriate suggestion.

Have a few files open in your editor to give GitHub Copilot a bigger picture of your project. You can also use #editor in the chat interface to provide GitHub Copilot with additional context on your currently opened files in Visual Studio Code (VS Code) and Visual Studio.

Remember to close unneeded files when context switching or moving on to the next task.

2. Provide a top-level comment

Just as you would give a brief, high-level introduction to a coworker, a top-level comment in the file you’re working in can help GitHub Copilot understand the overall context of the pieces you will be creating—especially if you want your AI assistant to generate the boilerplate code for you to get going.

Be sure to include details about what you need and provide a good description so it has as much information as possible. This will help to guide GitHub Copilot to give better suggestions, and give it a goal on what to work on. Having examples, especially when processing data or manipulation strings, helps quite a bit.

index.js file with a comment at the top asking Copilot to create a HomePage Component following detailed guidelines: a H1 text with label, a text area with a button, and a server response displaying facts returned

3. Set Includes and references

It’s best to manually set the includes/imports or module references you need for your work, particularly if you’re working with a specific version of a package.

GitHub Copilot will make suggestions, but you know what dependencies you want to use. This can also help to let GitHub Copilot know what frameworks, libraries, and their versions you’d like it to use when crafting suggestions.

This can be helpful to jump start GitHub Copilot to a newer library version when it defaults to providing older code suggestions.

4. Meaningful names matter

The name of your variables and functions matter. If you have a function named foo or bar, GitHub Copilot will not be able to give you the best completion because it isn’t able to infer intent from the names.

Just as the function name fetchData() won’t mean much to a coworker (or you after a few months), fetchData() won’t mean much to GitHub Copilot either.

Implementing good coding practices will help you get the most value from GitHub Copilot. While GitHub Copilot helps you code and iterate faster, remember the old rule of programming still applies: garbage in, garbage out.

function named "fetchAirports" that gets data from the /airport route and returns json output of airports to demonstrate meaningful names.

5. Provide specific and well- scoped function comments

Commenting your code helps you get very specific, targeted suggestions.

A function name can only be so descriptive without being overly long, so function comments can help fill in details that GitHub Copilot might need to know. One of the neat features about GitHub Copilot is that it can determine the correct comment syntax that is typically used in your programming language for function / method comments and will help create them for you based on what the code does. Adding more detail to these as the first change you do then helps GitHub Copilot determine what you would like to do in code and how to interact with that function.

Remember: Single, specific, short comments help GitHub Copilot provide better context.

6. Provide sample code

Providing sample code to GitHub Copilot will help it determine what you’re looking for. This helps to ground the model and provide it with even more context.

It also helps GitHub Copilot generate suggestions that match the language and tasks you want to achieve, and return suggestions based on your current coding standards and practices. Unit tests provide one level of sample code at the individual function/method level, but you can also provide code examples in your project showing how to do things end to end. The cool thing about using GitHub Copilot long-term is that it nudges us to do a lot of the good coding practices we should’ve been doing all along.

Learn more about providing context to GitHub Copilot by watching this Youtube video:

Inline Chat with GitHub Copilot

Inline chat

Outside of providing enough context, there are some built-in features of GitHub Copilot that you may not be taking advantage of. Inline chat, for example, gives you an opportunity to almost chat with GitHub Copilot between your lines of code. By pressing CMD + I (CTRL + I on Windows) you’ll have Copilot right there to ask questions. This is a bit more convenient for quick fixes instead of opening up GitHub Copilot Chat’s side panel.

This experience provides you with code diffs inline, which is awesome. There are also special slash commands available like creating documentation with just the slash of a button!

inline chat in the VS Code editor with the /doc command in focus

Tips and tricks with GitHub Copilot Chat

GitHub Copilot Chat provides an experience in your editor where you can have a conversation with the AI assistant. You can improve this experience by using built-in features to make the most out of it.

8. Remove irrelevant requests

For example, did you know that you can delete a previously asked question in the chat interface to remove it from the indexed conversation? Especially if it is no longer relevant?

Copilot Chat interface with a mouse click hovered over a conversation and the X button to delete it.

Doing this will improve the flow of conversation and give GitHub Copilot only the necessary information needed to provide you with the best output.

9. Navigate through your conversation

Another tip I found is to use the up and down arrows to navigate through your conversation with GitHub Copilot Chat. I found myself scrolling through the chat interface to find that last question I asked, then discovered I can just use my keyboard arrows just like in the terminal!

10. Use the @workspace agent

If you’re using VS Code or Visual Studio, remember that agents are available to help you go even further. The @workspace agent for example, is aware of your entire workspace and can answer questions related to it. As such, it can provide even more context when trying to get a good output from GitHub Copilot.

11. Highlight relevant code

Another great tip when using GitHub Copilot Chat is to highlight relevant code in your files before asking it questions. This will help to give targeted suggestions and just provides the assistant with more context into what you need help with.

12. Organize your conversations with threads

You can have multiple ongoing conversations with GitHub Copilot Chat on different topics by isolating your conversations with threads. We’ve provided a convenient way for you to start new conversations (thread) by clicking the + sign on the chat interface.

copilot chat interface with a mouse click on the plus button to start a new thread or conversation

13. Slash Commands for common tasks

Slash commands are awesome, and there are quite a few of them. We have commands to help you explain code, fix code, create a new notebook, write tests, and many more. They are just shortcuts to common prompts that we’ve found to be particularly helpful in day-to-day development from our own internal usage.

Command Description Usage
/explain Get code explanations Open file with code or highlight code you want explained and type:

/explain what is the fetchPrediction method?

/fix Receive a proposed fix for the problems in the selected code Highlight problematic code and type:

/fix propose a fix for the problems in fetchAirports route

/tests Generate unit tests for selected code Open file with code or highlight code you want tests for and type:

/tests

/help Get help on using Copilot Chat Type:

/help what can you do?

/clear Clear current conversation Type:

/clear

/doc Add a documentation comment Highlight code and type:

/doc

You can also press CMD+I in your editor and type /doc/ inline

/generate Generate code to answer your question Type:

/generate code that validates a phone number

/optimize Analyze and improve running time of the selected code Highlight code and type:

/optimize fetchPrediction method

/clear Clear current chat Type:

/clear

/new Scaffold code for a new workspace Type:

/new create a new django app

/simplify Simplify the selected code Highlight code and type:

/simplify

/feedback Provide feedback to the team Type:

/feedback

See the following image for commands available in VS Code:

 slash commands in VS Code terminal. commands shown are listed in the table above

14. Attach relevant files for reference

In Visual Studio and VS Code, you can attach relevant files for GitHub Copilot Chat to reference by using #file. This scopes GitHub Copilot to a particular context in your code base and provides you with a much better outcome.

To reference a file, type # in the comment box, choose #file and you will see a popup where you can choose your file. You can also type #file_name.py in the comment box. See below for an example:

15. Start with GitHub Copilot Chat for faster debugging

These days whenever I need to debug some code, I turn to GitHub Copilot Chat first. Most recently, I was implementing a decision tree and performed a k-fold cross-validation. I kept getting the incorrect accuracy scores and couldn’t figure out why. I turned to GitHub Copilot Chat for some assistance and it turns out I wasn’t using my training data set (X_train, y_train), even though I thought I was:

https://platform.twitter.com/widgets.js

I figured this out a lot faster than I would’ve with external resources. I want to encourage you to start with GitHub Copilot Chat in your editor to get debugging help faster instead of going to external resources first. Follow my example above by explaining the problem, pasting the problematic code, and asking for help. You can also highlight the problematic code in your editor and use the /fix command in the chat interface.

Be on the lookout for sparkles!

In VS Code, you can quickly get help from GitHub Copilot by looking out for “magic sparkles.” For example, in the commit comment section, clicking the magic sparkles will help you generate a commit message with the help of AI. You can also find magic sparkles inline in your editor as you’re working for a quick way to access GitHub Copilot inline chat.

Pressing them will use AI to help you fill out the data and more magic sparkles are being added where we find other places for GitHub Copilot to help in your day-to-day coding experience.

Know where your AI assistant shines

To get the best and most out of the tool, remember that context and prompt crafting is essential to keep in mind. Understanding where the tool shines best is also important. Some of the things GitHub Copilot is very good at include boilerplate code and scaffolding, writing unit tests, writing documentation, pattern matching, explaining uncommon or confusing syntax, cron jobs, and regex, and helping you remember things you’ve forgotten and debugging.

But never forget that you are in control, and GitHub Copilot is here as just that, your copilot. It is a tool that can help you write code faster, and it’s up to you to decide how to best use it.

It is not here to do your work for you or to write everything for you. It will guide you and nudge you in the right direction just as a coworker would if you asked them questions or for guidance on a particular issue.

I hope these tips and best practices were helpful. You can significantly improve your coding efficiency and output by properly leveraging GitHub Copilot. Learn more about how GitHub Copilot works by reading Inside GitHub: Working with the LLMs behind GitHub Copilot and Customizing and fine-tuning LLMs: What you need to know.

Harness the power of GitHub Copilot. Learn more or get started now.

The post Using GitHub Copilot in your IDE: Tips, tricks, and best practices appeared first on The GitHub Blog.

Hard and soft skills for developers coding in the age of AI

Post Syndicated from Sara Verdi original https://github.blog/2024-03-07-hard-and-soft-skills-for-developers-coding-in-the-age-of-ai/


As AI continues to shape the development landscape, developers are navigating a new frontier—not one that will make their careers obsolete, but one that will require their skills and instincts more than ever.

Sure, AI is revolutionizing software development, but that revolution ultimately starts and stops with developers. That’s because these tools need to have a pilot in control. While they can improve the time to code and ship, they can’t serve as a replacement for human oversight and coding abilities.

We recently conducted research into the evolving relationship between developers and AI tools and found that AI has the potential to alleviate the cognitive burden of complex tasks for developers. Instead of being used solely as a second pair of hands, AI tools can also be used more like a second brain, helping developers be more well-rounded and efficient.

In essence, AI can reduce mental strain so that developers can focus on anything from learning a new language to creating high-quality solutions for complex problems. So, if you’re sitting here wondering if you should learn how to code or how AI fits into your current coding career, we’re here to tell you what you need to know about your work in the age of AI.

A brief history of AI-powered techniques and tools

While the media buzz around generative AI is relatively new, AI coding tools have been around —in some form or another—much longer than you might expect. To get you up to speed, here’s a brief timeline of the AI-powered tools and techniques that have paved the way for the sophisticated coding tools we have today:

1950s: Autocoder was one of the earliest attempts at automatic coding. Developed in the 1950s by IBM, Autocoder translated symbolic language into machine code, streamlining programming tasks for early computers.

1958: LISP, one of the oldest high-level programming languages created by John McCarthy, introduced symbolic processing and recursive functions, laying the groundwork for AI programming. Its flexibility and expressive power made it a popular choice for AI research and development.

(defun factorial (n)
(if (<= n 1)
1
(* n (factorial (- n 1)))))


This function calculates the factorial of a non-negative integer ‘n’ in LISP. If ‘n’ is 0 or 1, the factorial is 1. Otherwise, it recursively multiplies ‘n’ by the factorial of n-1 until ‘n’ reaches 1.

1970: SHRDLU, developed by Terry Winograd at MIT, was an early natural language understanding program that could interpret and respond to commands in a restricted subset of English, and demonstrated the potential for AI to understand and generate human language.

SHRDLU, operating in a block world, aimed to understand and execute natural language instructions for manipulating virtual objects made of various shaped blocks.

SHRDLU, operating in a block world, aimed to understand and execute natural language instructions for manipulating virtual objects made of various shaped blocks.
[Source: Cryptlabs]

1980s: In the 1980s, code generators, such as The Last One, emerged as tools that could automatically generate code based on user specifications or predefined templates. While not strictly AI-powered in the modern sense, they laid the foundation for later advancements in code generation and automation.

“Personal Computer” magazine cover from 1982 that explored the program, The Last One.


“Personal Computer” magazine cover from 1982 that explored the program, The Last One.
[Source: David Tebbutts]

1990s: Neural network–based predictive models were increasingly applied to code-related tasks, such as predicting program behavior, detecting software defects, and analyzing code quality. These models leveraged the pattern recognition capabilities of neural networks to learn from code examples and make predictions.

2000s: Refactoring tools with AI capabilities began to emerge in the 2000s, offering automated assistance for restructuring and improving code without changing its external behavior. These tools used AI techniques to analyze code patterns, identify opportunities for refactoring, and suggest appropriate refactorings to developers.

These early AI-powered coding tools helped shape the evolution of software development and set the stage for today’s AI-driven coding assistance and automation tools, which continue to evolve seemingly every day.

Evolving beyond the IDE

Initially, AI tools were primarily confined to the integrated development environment (IDE), aiding developers in writing and refining code. But now, we’re starting to see AI touch every part of the software development lifecycle (SDLC), which we’ve found can increase productivity, streamline collaboration, and accelerate innovation for engineering teams.

In a 2023 survey of 500 U.S.-based developers, 70% reported experiencing significant advantages in their work, while over 80% said these tools will foster greater collaboration within their teams. Additionally, our research revealed that developers, on average, complete tasks up to 55% faster when using AI coding tools.

Here’s a quick look at where modern AI-powered coding tools are and some of the technical benefits they provide today:

  • Code completion and suggestions. Tools like GitHub Copilot use large language models (LLMs) to analyze code context and generate suggestions to make coding more efficient. Developers can now experience a notable boost in productivity as AI can suggest entire lines of code based on the context and patterns learned from developers’ code repositories, rather than just the code in the editor. Copilot also leverages the vast amount of open-source code available on GitHub to enhance its understanding of various programming languages, frameworks, and libraries, to provide developers with valuable code suggestions.
  • Generative AI in your repositories. Developers can use tools like GitHub Copilot Chat to ask questions and gain a deeper understanding of their code base in real time. With AI gathering context of legacy code and processes within your repositories, GitHub Copilot Enterprise can help maintain consistency and best practices across an organization’s codebase when suggesting solutions.
  • Natural language processing (NLP). AI has recently made great strides in understanding and generating code from natural language prompts. Think of tools like ChatGPT where developers can describe their intent in plain language, and the AI produces valuable outputs, such as executable code or explanations for that code functionality.
  • Enhanced debugging with AI. These tools can analyze code for potential errors, offering possible fixes by leveraging historical data and patterns to identify and address bugs more effectively.

To implement AI tools, developers need technical skills and soft skills

There are two different subsets of skills that can help developers as they begin to incorporate AI tools into their development workflows: technical skills and soft skills. Having both technical chops and people skills is super important for developers when they’re diving into AI projects—they need to know their technical skills to make those AI tools work to their advantage, but they also need to be able to work well with others, solve problems creatively, and understand the big picture to make sure the solutions they come up with actually hit the mark for the folks using them.

Let’s take a look at those technical skills first.

Getting technical

Prompt engineering

Prompt engineering involves crafting well-designed prompts or instructions that guide the behavior of AI models to produce desired outputs or responses. It can be pretty frustrating when AI-powered coding assistants don’t generate a valuable output, but that can often be quickly remedied by adjusting how you communicate with the AI. Here are some things to keep in mind when crafting natural language prompts:

  • Be clear and specific. Craft direct and contextually relevant prompts to guide AI models more effectively.
  • Experiment and iterate. Try out various prompt variations and iterate based on the outputs you receive.
  • Validate, validate, validate. Similar to how you would inspect code written by a colleague, it’s crucial to consistently evaluate, analyze, and verify code generated by AI algorithms.

Code reviews

AI is helpful, but it isn’t perfect. While LLMs are trained on large amounts of data, they don’t inherently understand programming concepts the way humans do. As a result, the code they generate may contain syntax errors, logic flaws, or other issues. That’s why developers need to rely on their coding competence and organizational knowledge to make sure that they aren’t pushing faulty code into production.

For a successful code review, you can start out by asking: does this code change accomplish what it is supposed to do? From there, you can take a look at this in-depth checklist of more things to keep in mind when reviewing AI-generated code suggestions.

Testing and security

With AI’s capabilities, developers can now generate and automate tests with ease, making their testing responsibilities less manual and more strategic. To ensure that the AI-generated tests cover critical functionality, edge cases, and potential vulnerabilities effectively, developers will need a strong foundational knowledge of programming skills, testing principles, and security best practices. This way, they’ll be able to interpret and analyze the generated tests effectively, identify potential limitations or biases in the generated tests, and augment with manual tests as necessary.

Here’s a few steps you can take to assess the quality and reliability of AI-generated tests:

  • Verify test assertions. Check if the assertions made by the AI-generated tests are verifiable and if they align with the expected behavior of the software.
  • Assess test completeness. Evaluate if the AI-generated tests cover all relevant scenarios and edge cases and identify any gaps or areas where additional testing may be required to achieve full coverage.
  • Identify limitations and biases. Consider factors such as data bias, algorithmic biases, and limitations of the AI model used for test generation.
  • Evaluate results. Investigate any test failures or anomalies to determine their root causes and implications for the software.

For those beginning their coding journey, check out the GitHub Learning Pathways to gain deeper insights into testing strategies and security best practices with GitHub Actions and GitHub Advanced Security.
You can also bolster your security skills with this new, open source Secure Code Game 🎮.

And now, the soft skills

As developers leverage AI to build what’s next, having soft skills—like the ability to communicate and collaborate well with colleagues—is becoming more important than ever.

Let’s take a more in-depth look at some soft skills that developers can focus on as they continue to adopt AI tools:

  • Communication. Communication skills are paramount to collaborating with team members and stakeholders to define project requirements, share insights, and address challenges. They’re also important as developers navigate prompt engineering. The best AI prompts are clear, direct, and well thought out—and communicating with fellow humans in the workplace isn’t much different.
Did you know that prompt engineering best practices just might help you build your communication skills with colleagues? Check out this thought piece from Harvard Business Review for more insights.
  • Problem solving. Developers may encounter complex challenges or unexpected issues when working with AI tools, and the ability to think creatively and adapt to changing circumstances is crucial for finding innovative solutions.
  • Adaptability. The rapid advancement of AI technology requires developers to be adaptable and willing to embrace new tools, methodologies, and frameworks. Plus, cultivating soft skills that promote a growth mindset allows individuals to consistently learn and stay updated as AI tools continue to evolve.
  • Ethical thinking. Ethical considerations are important in AI development, particularly regarding issues such as bias, fairness, transparency, and privacy. Integrity and ethical reasoning are essential for making responsible decisions that prioritize the well-being of users and society at large.
  • Empathy. Developers are often creating solutions and products for end users, and to create valuable user experiences, developers need to be able to really understand the user’s needs and preferences. While AI can help developers create these solutions faster, through things like code generation or suggestions, developers still need to be able to QA the code and ensure that these solutions still prioritize the well-being of diverse user groups.

Sharpening these soft skills can ultimately augment a developer’s technical expertise, as well as enable them to work more effectively with both their colleagues and AI tools.

Take this with you

As AI continues to evolve, it’s not just changing the landscape of software development; it’s also poised to revolutionize how developers learn and write code. AI isn’t replacing developers—it’s complementing their work, all while providing them with the opportunity to focus more on coding and building their skill sets, both technical and interpersonal.

If you’re interested in improving your skills along your AI-powered coding journey, check out these repositories to start building your own AI based projects. Or you can test out GitHub Copilot, which can help you learn new programming languages, provide coding suggestions, and ask important coding questions right in your terminal.

The post Hard and soft skills for developers coding in the age of AI appeared first on The GitHub Blog.

How AI code generation works

Post Syndicated from Jeimy Ruiz original https://github.blog/2024-02-22-how-ai-code-generation-works/


Generative AI coding tools are changing software production for enterprises. Not just for their code generation abilities—from vulnerability detection and facilitating comprehension of unfamiliar codebases, to streamlining documentation and pull request descriptions, they’re fundamentally reshaping how developers approach application infrastructure, deployment, and their own work experience.

We’re now witnessing a significant turning point. As AI models get better, refusing adoption would be like “asking an office worker to use a typewriter instead of a computer,” says Albert Ziegler, principal researcher and member of the GitHub Next research and development team.

In this post, we’ll dive into the inner workings of AI code generation, exploring how it functions, its capabilities and benefits, and how developers can use it to enhance their development experience while propelling your enterprise forward in today’s competitive landscape.

How to use AI to generate code

AI code generation refers to full or partial lines of code that are generated by machines instead of human developers. This emerging technology leverages advanced machine learning models, particularly large language models (LLMs), to understand and replicate the syntax, patterns, and paradigms found in human-generated code.

The AI models powering these tools, like ChatGPT and GitHub Copilot, are trained on natural language text and source code from publicly available sources that include a diverse range of code examples. This training enables them to understand the nuances of various programming languages, coding styles, and common practices. As a result, the AI can generate code suggestions that are syntactically correct and contextually relevant based on input from developers.

Favored by 55% of developers, our AI-powered pair programmer, GitHub Copilot, provides contextualized coding assistance based on your organization’s codebase across dozens of programming languages, and targets developers of all experience levels. With GitHub Copilot, developers can use AI to generate code in three ways:

1. Type code and AI can autocomplete the code

Autocompletions are the earliest version of AI code generation. John Berryman, a senior researcher of ML on the GitHub Copilot team, explains the user experience: “I’ll be writing code and taking a pause to think. While I’m doing that, the agent itself is also thinking, looking at surrounding code and content in neighboring tabs. Then it pops up on the screen as gray ‘ghost text’ that I can reject, partially accept, or fully accept and then, if necessary, modify.”

While every developer can reap the benefits of using AI coding tools, experienced programmers can often feel these gains even more so. “In many cases, especially for experienced programmers in a familiar environment, this suggestion speeds us up. I would have written the same thing. It’s just faster to hit ‘tab’ (thus accepting the suggestion) than it is to write out those 20 characters by myself,” says Johan Rosenkilde, principal researcher for GitHub Next.

Whether developers are new or highly skilled, they’ll often have to work in less familiar languages, and code completion suggestions using GitHub Copilot can lend a helping hand. “Using GitHub Copilot for code completion has really helped speed up my learning experience,” says Berryman. “I will often accept the suggestion because it’s something I wouldn’t have written on my own since I don’t know the syntax.”

Using an AI coding tool has become an invaluable skill in itself. Why? Because the more developers practice coding with these tools, the faster they’ll get at using them.

2. Explicit code comments codes using natural language to receive even better AI-generated code suggestions

For experienced developers in unfamiliar environments, tools like GitHub Copilot can even help jog their memories.

Let’s say a developer imports a new type of library they haven’t used before, or that they don’t remember. Maybe they’re looking to figure out the standard library function or the order of the argument. In these cases, it can be helpful to make GitHub Copilot more explicitly aware of where the developer wants to go by writing a comment.

“It’s quite likely that the developer might not remember the formula, but they can recognize the formula, and GitHub Copilot can remember it by being prompted,” says Rosenkilde. This is where natural language commentary comes into play: it can be a shortcut for explaining intent when the developer is struggling with the first few characters of code that they need.

If developers give specific names to their functions and variables, and write documentation, they can get better suggestions, too. That’s because GitHub Copilot can read the variable names and use them as an indicator for what that function should do.

Suddenly that changes how developers write code for the better, because code with good variable and function names are more maintainable. And oftentimes the main job of a programmer is to maintain code, not write it from scratch.

“When you push that code, someone is going to review it, and they will likely have a better time reviewing that code if it’s well named, if there’s even a hint of documentation in it, and so on,” says Rosenkilde. In this sense, the symbiotic relationship between the developer and the AI coding tool is not just beneficial for the developer, but for the entire team.

3. Chat directly with AI

With AI chatbots, code generation can be more interactive. GitHub Copilot Chat, for example, allows developers to interact with code by asking it to explain code, improve syntax, provide ideas, generate tests, and modify existing code—making it a versatile ally in managing coding tasks.

Rosenkilde uses the different functionalities of GitHub Copilot:

“When I want to do something and I can’t remember how to do it, I type the first few letters of it, and then I wait to see if Copilot can guess what I’m doing,” he says. “If that doesn’t work, maybe I delete those characters and I write a one liner in commentary and see whether Copilot can guess the next line. If that doesn’t work, then I go to Copilot Chat and explain in more detail what I want done.”

Typically, Copilot Chat returns with something much more verbose and complete than what you get from GitHub Copilot code completion. “Namely, it describes back to you what it is you want done and how it can be accomplished. It gives you code examples, and you can respond and say, oh, I see where you’re going. But actually I meant it like this instead,” says Rosenkilde.

But using AI chatbots doesn’t mean developers should be hands off. Mistakes in reasoning could lead the AI down a path of further mistakes if left unchecked. Berryman recommends that users should interact with the chat assistant in much the same way that you would when pair programming with a human. “Go back and forth with it. Tell the assistant about the task you are working on, ask it for ideas, have it help you write code, and critique and redirect the assistant’s work in order to keep it on the right track.”

The importance of code reviews

GitHub Copilot is designed to empower developers to execute their ideas. As long as there is some context for it to draw on, it will likely generate the type of code the developer wants. But this doesn’t replace code reviews between developers.

Code reviews play an important role in maintaining code quality and reliability in software projects, regardless of whether AI coding tools are involved. In fact, the earlier developers can spot bugs in the code development process, the cheaper it is by orders of magnitude.

Ordinary verification would be: does the code parse? Do the tests work? With AI code generation, Ziegler explains that developers should, “Scrutinize it in enough detail so that you can be sure the generated code is correct and bug-free. Because if you use tools like that in the wrong way and just accept everything, then the bugs that you introduce are going to cost you more time than you save.”

Rosenkilde adds, “A review with another human being is not the same as that, right? It’s a conversation between two developers about whether this change fits into the kind of software they’re building in this organization. GitHub Copilot doesn’t replace that.”

The advantages of using AI to generate code

When developer teams use AI coding tools across the software development cycle, they experience a host of benefits, including:

Faster development, more productivity

AI code generation can significantly speed up the development process by automating repetitive and time-consuming tasks. This means that developers can focus on high-level architecture and problem-solving. In fact, 88% of developers reported feeling more productive when using GitHub Copilot.

Rosenkilde reflects on his own experience with GitHub’s AI pair programmer: “95% of the time, Copilot brings me joy and makes my day a little bit easier. And this doesn’t change the code I would have written. It doesn’t change the way I would have written it. It doesn’t change the design of my code. All it does is it makes me faster at writing that same code.” And Rosenkilde isn’t alone: 60% of developers feel more fulfilled with their jobs when using GitHub Copilot.

Mental load alleviated

The benefits of faster development aren’t just about speed: they’re also about alleviating the mental effort that comes with completing tedious tasks. For example, when it comes to debugging, developers have to reverse engineer what went wrong. Detecting a bug can involve digging through an endless list of potential hiding places where it might be lurking, making it repetitive and tedious work.

Rosenkilde explains, “Sometimes when you’re debugging, you just have to resort to creating print statements that you can’t get around. Thankfully, Copilot is brilliant at print statements.”

A whopping 87% of developers reported spending less mental effort on repetitive tasks with the help of GitHub Copilot.

Less context switching

In software development, context switching is when developers move between different tasks, projects, or environments, which can disrupt their workflow and decrease productivity. They also often deal with the stress of juggling multiple tasks, remembering syntax details, and managing complex code structures.

With GitHub Copilot developers can bypass several levels of context switching, staying in their IDE instead of searching on Google or jumping into external documentation.

“When I’m writing natural language commentary,” says Rosenkilde, “GitHub Copilot code completion can help me. Or if I use Copilot Chat, it’s a conversation in the context that I’m in, and I don’t have to explain quite as much.”

Generating code with AI helps developers offload the responsibility of recalling every detail, allowing them to focus on higher-level thinking, problem-solving, and strategic planning.

Berryman adds, “With GitHub Copilot Chat, I don’t have to restate the problem because the code never leaves my trusted environment. And I get an answer immediately. If there is a misunderstanding or follow-up questions, they are easy to communicate with.”

What to look for in enterprise-ready AI code generation tools

Before you implement any AI into your workflow, you should always review and test tools thoroughly to make sure they’re a good fit for your organization. Here are a few considerations to keep in mind.

Compliance

  • Regulatory compliance. Does the tool comply with relevant regulations in your industry?
  • Compliance certifications. Are there attestations that demonstrate the tool’s compliance with regulations?

Security

  • Encryption. Is the data transmission and storage encrypted to protect sensitive information?
  • Access controls. Are you able to implement strong authentication measures and access controls to prevent unauthorized access?
  • Compliance with security standards. Is the tool compliant with industry standards?
  • Security audits. Does the tool undergo regular security audits and updates to address vulnerabilities?

Privacy

  • Data handling. Are there clear policies for handling user data and does it adhere to privacy regulations like GDPR, CCPA, etc.?
  • Data anonymization. Does the tool support anonymization techniques to protect user privacy?

Permissioning

  • Role-based access control. Are you able to manage permissions based on user roles and responsibilities?
  • Granular permissions. Can you control access to different features and functionalities within the tool?
  • Opt-in/Opt-out mechanisms. Can users control the use of their data and opt out if needed?

Pricing

  • Understand the pricing model. is it based on usage, number of users, features, or other metrics?
  • Look for transparency. Is the pricing structure clear with no hidden costs?
  • Scalability. Does the pricing scale with your usage and business growth?

Additionally, consider factors such as customer support, ease of integration with existing systems, performance, and user experience when evaluating AI coding tools. Lastly, it’s important to thoroughly assess how well the tool aligns with your organization’s specific requirements and priorities in each of these areas.

Visit the GitHub Copilot Trust Center to learn more around security, privacy, and other topics.

Can AI code generation be detected?

The short answer here is: maybe.

Let’s first give some context to the question. It’s never really the case that a whole code base is generated with AI, because large chunks of AI-generated code are very likely to be wrong. The standard code review process is a good way to avoid this, since large swaths of completely auto-generated code would stand out to a human developer as simply not working.

For smaller amounts of AI-generated code, there is no way at the moment to detect traces of AI in code with true confidence. There are offerings that purport to classify whether content has AI-generated text, but there are limited equivalents for code, since you’d need a dedicated model to do it. Ziegler explains, “Computer generated code is good enough that it doesn’t leave any particular traces and normally has no clear tells.”

At GitHub, the Copilot team makes use of a duplicate detection filter that detects exact duplicates in code. So, if you’re writing code and it’s an exact copy of something that exists elsewhere, then it’ll flag it.

Is AI code generation secure?

AI code generation is not any more insecure than human generated code. A combination of testing, manual code reviews, scanning, monitoring, and feedback loops can produce the same quality of code as your human-generated code.

When it comes to code generated by GitHub Copilot, developers can use tools like code scanning, which actively reviews your code for potential security issues in real-time and seamlessly integrates the findings into the developer workflow.

Ultimately, AI code generation will have vulnerabilities—but so does code written by human developers. As Ziegler explains, “It’s unclear whether computer generated code does particularly worse. So, the answer is not if you have GitHub Copilot, use a vulnerability checker. The answer is always use a vulnerability checker.”

Watch this video for more tips and words of advice around secure coding best practices with AI.

Empower your enterprise with AI code generation

While the benefits to using AI code generation tools can be significant, it’s important to note that human oversight remains crucial to ensure that the generated code aligns with project goals, coding standards, and business needs.

Tech leaders should embrace the use of AI code generation—not only to streamline development, but also to empower developer teams to collaborate, drive meaningful business outcomes, and deliver exceptional value to customers.

Learn more or get started with the world’s most widely adopted AI developer tool.

Want to learn how GitHub can help your organization do more with AI?

At GitHub Galaxy 2024, we’ll explore cutting-edge research and best practices in the rapidly evolving world of AI—empowering your business to maximize productivity and innovate at scale.

Register now >

The post How AI code generation works appeared first on The GitHub Blog.

10 unexpected ways to use GitHub Copilot

Post Syndicated from Kedasha Kerr original https://github.blog/2024-01-22-10-unexpected-ways-to-use-github-copilot/

Writing code is more than just writing code. There’s commit messages to write, CLI commands to execute, and obscure syntax to try to remember. While you’ve probably used GitHub Copilot to support your coding, did you know it can also support your other workloads?

GitHub Copilot is widely known for its ability to help developers write code in their IDE. Today, I want to show you how the AI assistant’s abilities can extend beyond just code generation. In this post, we’ll explore 10 use cases where GitHub Copilot can help reduce friction during your developer workflow. This includes pull requests, working from the command line, debugging CI/CD workflows, and much more!

Let’s get into it.

1. Run terminal commands from GitHub Copilot Chat

If you ever forget how to run a particular command when you’re working in your VS Code, GitHub Copilot Chat is here to help! With the new @terminal agent in VS Code, you can ask GitHub Copilot how to run a particular command. Once it generates a response, you can then click the “Insert into Terminal” button to run the suggested command.

Let me show you what I mean:

The @terminal agent in VS Code also has context about the integrated shell terminal, so it can help you even further.

2. Write pull request summaries (Copilot Enterprise feature only)

We’ve all been there where we made a sizable pull request with tons of files and hundreds of changes. But, sometimes, it can be hard to remember every little detail that we’ve implemented or changed.

Yet it’s an important part of collaborating with other engineers/developers on my team. After all, if I don’t give them a summary of my proposed changes, I’m not giving them the full context they need to provide an effective review. Thankfully, GitHub Copilot is now integrated into pull requests! This means, with the assistance of AI, you can generate a detailed pull request summary of the changes you made in your files.

Let’s look at how you can generate these summaries:

Now, isn’t that grand! All you have to do is go in and edit what was generated and you have a great, detailed explanation of all the changes you’ve made—with links to changed files!

Note: You will need a Copilot Enterprise plan (which requires GitHub Enterprise Cloud) to use PR summaries. Learn more about this enterprise feature by reading our documentation.

3. Generate commit messages

I came across this one recently while making changes in VS Code. GitHub Copilot can help you generate commit messages right in your IDE. If you click on the source control button, you’ll notice a sparkle in the message input box.

Click on those sparkles and voilà, commit messages are generated on your behalf:

I thought this was a pretty nifty feature of GitHub Copilot in VS Code and Visual Studio.

4. Get help in the terminal with GitHub Copilot in the CLI

Another way to get help with terminal commands is to use GitHub Copilot in the CLI. This is an extension to GitHub CLI that helps you with general shell commands, Git commands, and gh cli commands.

GitHub Copilot in the CLI is a game-changer that is super useful for reminding you of commands, teaching you new commands or explaining random commands you come across online.

Learn how to get started with GitHub Copilot in the CLI by reading this post!

5. Talk to your repositories on GitHub.com (Copilot Enterprise feature only)

If you’ve ever gone to a new repository and have no idea what’s happening even though the README is there, you can now use GitHub Copilot Chat to explain the repository to you, right in GitHub.com. Just click on the Copilot icon in the top right corner of the repository and ask whatever you want to know about that repository.

On GitHub.com you can ask Copilot general software related questions, questions about the context of your project, questions about a specific file, or specified lines of code within a file.

Note: You will need a Copilot Enterprise plan (which requires GitHub Enterprise Cloud) to use GitHub Copilot Chat in repositories on GitHub.com. Learn more about this enterprise feature by reading our documentation.

6. Fix code inline

Did you know that in addition to asking for suggestions with comments, you can get help with your code inline? Just highlight the code you want to fix, right click, and select “Fix using Copilot.” Copilot will then provide you with a suggested fix for your code.

This is great to have for those small little fixes we sometimes need right in our current files.

7. Bulk close 1000+ GitHub Issues

My team and I had a use case where we needed to close over 1,600 invalid GitHub Issues submitted to one of our repositories. I created a custom GitHub Action that automatically closed all 1,600+ issues and implemented the solution with GitHub Copilot.

GitHub Copilot Chat helped me to create the GitHub Action, and also helped me implement the closeIssue() function very quickly by leveraging Octokit to grab all the issues that needed to be closed.

Example of a closeissues.js script generated by GitHub Copilot

You can read all about how I bulk closed 1000+ GitHub issues in this blog post, but just know that with GitHub Copilot Chat, we went from having 1,600+ open issues, to a measly 64 in a matter of minutes.

8. Generate documentation for your code

We all love documenting our code, but just in case some of us need a little help writing documentation, GitHub Copilot is here to help!

Regardless of your language, you can quickly generate documentation following language specific formats—Docstring for Python, JSDoc for Javascript or Javadoc for Java.

9. Get help with error messages in your terminal

Error messages can often be confusing. With GitHub Copilot in your IDE, you can now get help with error messages right in the terminal. Just highlight the error message, right click, and select “Explain with Copilot.” GitHub Copilot will then provide you with a description of the error and a suggested fix.

You can also bring error messages from your browser console into Copilot Chat so it can explain those messages to you as well with the /explain slash command.

10. Debug your GitHub Actions workflow

Whenever I have a speaking engagement, I like to create my slides using Slidev, an open source presentation slide builder for developers. I enjoy using it because I can create my slides in Markdown and still make them look splashy! Take a look at this one for example!

Anyway, there was a point in time where I had an issue with deploying my slides to GitHub Pages and I just couldn’t figure out what the issue was. So, of course, I turned to my trusty assistant—GitHub Copilot Chat that helped me debug my way through deploying my slides.

Conversation between GitHub Copilot Chat and developer to debug a GitHub Actions workflow

Read more about how I debugged my deployment workflow with GitHub Copilot Chat here.

GitHub Copilot goes beyond code completion

As you see above, GitHub Copilot extends far beyond your editor and code completion. It is truly evolving to be one of the best tools you can have in your developer toolkit. I’m still learning and discovering new ways to integrate GitHub Copilot into my daily workflow and I hope you give some of the above a chance!

Be sure to sign up for Github Copilot if you haven’t tried it out yet and stay up to date with all that’s happening by subscribing to our developer newsletter for more tips, technical guides, and best practices! You can also drop me a note on X if you have any questions, @itsthatladydev.

Until next time, happy coding!

The post 10 unexpected ways to use GitHub Copilot appeared first on The GitHub Blog.

How we’re experimenting with LLMs to evolve GitHub Copilot

Post Syndicated from Sara Verdi original https://github.blog/2023-12-06-how-were-experimenting-with-llms-to-evolve-github-copilot/

Earlier this year, it seemed like every headline or dinner conversation was earmarked by the buzzwords “generative AI.” And while 2023 has been a benchmark year for the adoption of generative AI, it’s not entirely a new technology. Arguably, AI has been around since the ‘60s, but the AI as we know it today came to be with the invention of machine learning frameworks known as neural networks (you can read more about that here).

For the past few years at GitHub, we’ve been experimenting with generative AI models to create new, meaningful tools for developers—which is how GitHub Copilot was born. And since GitHub Copilot’s initial preview release in 2021, we’ve been thinking a lot about how generative AI can (and should) empower developers to be more productive at every stage of the software development lifecycle. That led us to our vision for the future of AI-powered software development with GitHub Copilot, which we covered in detail this year at GitHub Universe 2023.

In this blog post, we’ll explore some of the experiments we’ve conducted with generative AI models over the past few years, as well as take a behind-the-scenes look at some of our key learnings. We’ll also explore what going from a concept to a product looks like with a radically new technology.

Key pillars of experimentation with AI at GitHub

As developers increasingly use AI tools to improve overall productivity, we have four key pillars at GitHub that are guiding our work and how we experiment with AI. We want a developer’s AI experience to be:

  • Predictable. We want to create tools that guide developers towards their end goals but don’t suprise or overwhelm them.
  • Tolerable. As we’ve seen, AI models can be wrong. Users should be able to spot incorrect suggestions easily, and address them at a low cost to focus and productivity.
  • Steerable. When a response isn’t right or isn’t what a user is looking for, they should be able to steer the AI towards a solution. Otherwise, we’re optimistically banking on the models producing perfect answers.
  • Verifiable. Solutions must be easy to evaluate. The models are not perfect, but they can be very helpful tools if users verify their outputs.

Now that we have a baseline understanding of how we prioritize experimenting with AI, let’s take a look at the events that led to the conception of the latest evolution of GitHub Copilot.

Before GitHub Copilot’s evolution came GPT-4

Last year, researchers from GitHub Next, our R&D department focused on the future of software development, were given advanced access to OpenAI’s large language model (LLM) that would soon be released as GPT-4.

“At the time, no one had seen anything like this,” Idan Gazit, senior director of research for GitHub Next recalls. “It became a race to discover what the new models are capable of doing and what kinds of applications are possible tomorrow that were impossible yesterday.”

So, the GitHub Next team did what they do best: experiment. Over the course of several months, researchers from GitHub Next used the GPT-4 model to develop potential new tools and features that could be used across the GitHub platform. Once the team identified the projects that showed true value, the sprint to build began.

“In classic GitHub Next fashion, we sat down and spiked a bunch of ideas and saw what looked promising or exciting to us,” Gazit explains. “And then we doubled down on the things that we believed would bear fruit.”

In the time between receiving the model and the slated announcement of the model’s release in March 2023, the team had come up with several concepts and technical previews.

At the time, no one had seen anything like this. It became a race to discover what the new models are capable of doing and what kinds of applications are possible tomorrow that were impossible yesterday.

– Idan Gazit, Senior Director of Research // GitHub Next

As these projects came together, senior leadership at GitHub began to think about what these meant for the future of GitHub Copilot. Mario Rodriguez, VP of product management, says, “We knew we wanted to make an announcement of our own around the joint Microsoft and OpenAI announcement of GPT-4. At that time, GitHub Next had a set of investments that they were making that they thought were worthwhile for the announcement. Those investments were not production-ready—they were more future-focused.” He explains, “But that got us thinking, so we put pen to paper and came up with the ambition behind the latest evolution of GitHub Copilot.”

Thinking ahead 🤔

As teams at GitHub thought about evolving GitHub Copilot beyond a pair programmer in the IDE, they imagined a future where GitHub Copilot was:

  • Ubiquitous across every tool that developers use and integrated into every task that developers perform.
  • Conversational by default, so that natural language can be used to achieve anything.
  • Personalized to the context and knowledge of the individual, project, team, and community.

This thought exercise, in conjunction with GitHub Next’s work to conceptualize and create new tools that could revolutionize the developer workflow, crystallized what would make up the latest evolution of GitHub Copilot. And on March 22, 2023, the technical preview for what GitHub Copilot would evolve into was released to the world with GitHub Copilot Chat and the following technical previews created by GitHub Next:

So, what happened behind the scenes to come up with these previews? Let’s find out.

Experimenting with AI’s place in the developer experience

If you asked just about any developer what’s something that is specifically unique to GitHub, it would be pretty shocking if they didn’t say “pull requests.” Pull requests play a central role in the GitHub developer experience—they’re not only a point of collaboration, but a gateway for teams to view and approve any changes to code.

So when Andrew Rice, Don Syme, Devon Rifkin, Matt Rothenberg, Max Schaefer, Albert Ziegler, and Aqeel Siddiqui were given the GPT-4 model, they were tasked with the challenge of finding ways to incorporate AI into GitHub.com.

“GitHub invented pull requests, so we started thinking, how could we add AI smarts around pull requests?” Rice says. “We tried a bunch of stuff—we prototyped automatic code suggestions for reviews, we had a sort of summarize mode, and a bunch of other things around test generation.” But as the deadline of March 22 approached, a few of these prototyped features weren’t working as desired, so Rice and team began focusing their attention and efforts solely on the summary feature.

With the early version of Copilot for Pull Requests, a developer could submit their pull request and the AI model would generate a description and walkthrough of the code in the first comment to provide important context for the reviewer.

“We did an internal study of the feature with Hubbers and it didn’t go well,” Rice laughs. It wasn’t that the developers didn’t like what the feature was trying to achieve, it was the user experience, Rice believes, they were having challenges with. “The developers were concerned that the AI would be wrong. But there’s two things: you have the content the AI generates and then you have the way that it’s presented to the user and how it interacts with the workflow. At first, we focused a lot on the first bit, the AI-generated content, but it turned out that the second bit was far more crucial in getting this thing to fly,” he explains.

To work around this, Rice and team decided to pivot and use the same AI-generated content but frame it differently. “Instead of a comment, we put it as a suggestion to the developer that let them get a preview of what the description of their pull request could look like that they could then edit,” Rice says. “So, we moved it to a suggestion system, and all of a sudden the feedback changed to ‘wow, these are helpful suggestions.’ The content was exactly the same as before, it was just presented differently.”

Nobody’s perfect—not even AI

For Rice, the key takeaway during this process was the importance of how the AI output is presented to the developer, rather than the total accuracy of the suggestion. That doesn’t mean that it’s acceptable for the AI to be completely wrong, but it does mean that a developer’s demand for the quality of the suggestion sits on a spectrum—developers will view something as it fits within their workflow regardless of what is served to them. When the content was served as a suggestion that the developer had the authority to accept and edit, the typical attitude toward the feature changed.

Eddie Aftandilian, a principal researcher that headed up the development of another GitHub Copilot feature, shared some similar sentiments and takeaways throughout the process of building Copilot for Docs. In late 2022, Aftandilian and Johan Rosenkilde were examining embeddings and retrievals, and they prototyped a vector database for a different GitHub Copilot experiment. “This got us thinking, what if we could use this for retrievals of things other than just code,” Aftandilian remembers. “Once we got access to GPT-4, we realized we could use the retrieval engine to search a large corpus of documentation, and then compose those search results into a prompt that elicits better, more topical answers based on the documentation,” he explains.

“Since GitHub is all about developer tools, we thought, how can we make this into a useful developer tool?” Aftandilian says. Developers spend an enormous amount of time poring over docs to find solutions—and as Aftandilian plainly puts it, “No one really likes reading documentation!” He continues, “It also can be hard to get the right answer out of docs, too. So, it seemed like there was an opportunity here for something that could answer a developer’s question more directly and unblock them. It’s also an area of the development process that we felt was underexplored. We spend a lot of time searching around for answers, which can be a real pain point, and we thought we could do better with these new LLMs.”

Aftandilian, along with Devon Rifkin, Jake Donham, and Amelia Wattenberger, also deployed their early version of Copilot for Docs to Hubbers, extending GitHub Copilot’s reach to GitHub’s internal docs in addition to public documentation. But once the preview reached public testing, he got some interesting feedback about the quality of the AI outputs.

“One challenge we came across during the development process was that the models don’t always give the right answer or the right document,” Aftandilian says. “To address this, we built in the capability for our answers to provide references or links to other documentation. We found that when we deployed it, the feedback we received was that developers didn’t mind if the output wasn’t always perfectly correct if the linked references made it easier to evaluate what the AI produced. They were using Copilot for Docs as a search engine,” he says.

The UX needs to be tolerant of AI’s mistakes—you can’t assume that the AI will always be right.

– Eddie Aftandilian, Principal Researcher // GitHub Next

Another key learning for Aftandilian was that human feedback is the true gold standard for developing AI-based tools. “One of our conclusions was that you should ship something sooner rather than later to get real, human feedback to drive improvements,” he says.

And similar to Rice’s earlier point, user experience is also critical to the success of these AI-powered tools. “The UX needs to be tolerant of AI’s mistakes—you can’t assume that the AI will always be right,” Aftandilian says. “Initially we were focused on getting everything right, but we soon learned that the chat-like modality of Copilot for Docs makes the answers feel less authoritative and folks are more tolerant of the responses when they point the user in the right direction. The AI isn’t always perfect, but it’s a great start.”

Small but mighty

In October 2022, the entire GitHub Next team met up in Oxford, England to get together and discuss all of the projects that they were currently working on, as well as some exciting—and maybe even far-fetched—ideas.

“One of the things that I pitched at this crazy ideas session was a project that would use LLMs to help you figure out CLI commands,” Johan Rosenkilde, a principal researcher for GitHub Next, recalls. “I was thinking about something that could use natural language prompts to describe what you wanted to do in the command line, then some sort of GUI or interface pops up that helps you narrow down what you want to do.”

As Rosenkilde talked through his pitch, one of his colleagues, Matt Rothenberg, began writing an application that did almost exactly that. “By the time my talk ended, he asked if he could show me something, and my mind was just blown,” Rosenkilde laughs. That thirty-minute prototype was the genesis for what would become Copilot for CLI.

“What he had created clearly showed that there was something of value here, but it lacked maturity of course,” Rosenkilde says. “And so what we did was carve out time to refine this rough demo into something that we could deliver to developers,” he says. By the time March 2023 rolled around, they had a preview that brought the power of GitHub Copilot right to the CLI for developers to quickly ask for and receive their desired shell commands, including a breakdown that explains each part of the command—without ever needing to search the web for answers.

When reflecting on the process of taking this app from that original, scrappy version to a technical preview, Rosenkilde echoes Rice and Aftandilian in his appreciation for the subtlety of UX decisions.

“I’m a backend person: I’m heavy on theory and I like really difficult problems that cause me to think for weeks about a solution,” Rosenkilde says. “Matt was the UX guy, and he iterated extremely quickly through a lot of options. So much of the success of this application hinged on the UX, and that’s a lesson that I’ve taken with me. All that we do in GitHub Next, in the end, is think up tools that will add value to the user experience, so it’s crucial that we get the design right and that it fits in with what the AI model can do. As we know, the AI models aren’t perfect, but when they are imperfect, the cost to the user should be as low as possible,” Rosenkilde says.

That simple fact is what informs the explanation field that can be found in Copilot for CLI. “This actually wasn’t part of the original UI. As the product matured, we came up with the explanation field, but we had some difficulty with the LLM producing the structured type of explanations we sought. It’s very unnatural for a language model to produce something that looks like this, I had to hit it with a very large hammer,” he jokes. “We wanted it to be clearly structured, but if you just ask the AI to explain a shell command, it would feed you a long paragraph that is not readily scannable and might not include the details you want.”

Example of the explanation field in Copilot for CLI

Rosenkilde also felt that it was important to add the explanation field to help developers learn about shell scripts and double check that they have received the correct command. “It’s also a security feature because you can read in natural language whether the command will change files you didn’t expect to change,” he explains. This multifaceted explanation field is not only useful, it’s a testament to the UX of the application. “When you have such a small application, you want every feature to have multiple different uses so that you can package up a lot of complexity in something that visually is very simple.”

Where we’re headed 🚀

We’re focused on something great here: creating delightful AI experiences for everyone who interacts with the GitHub platform. And while we’re working on it, we invite you to be part of the process. You can get involved by joining the waitlists for our current previews and giving us your honest feedback on what you think and what you want to see going forward.

And if you’re not already using GitHub Copilot, give it a try with a free, 30-day trial for individual developers.

The post How we’re experimenting with LLMs to evolve GitHub Copilot appeared first on The GitHub Blog.

Demystifying LLMs: How they can do things they weren’t trained to do

Post Syndicated from Jeimy Ruiz original https://github.blog/2023-10-27-demystifying-llms-how-they-can-do-things-they-werent-trained-to-do/

Large language models (LLMs) are revolutionizing the way we interact with software by combining deep learning techniques with powerful computational resources.

While this technology is exciting, many are also concerned about how LLMs can generate false, outdated, or problematic information, and how they sometimes even hallucinate (generating information that doesn’t exist) so convincingly. Thankfully, we can immediately put one rumor to rest. According to Alireza Goudarzi, senior researcher of machine learning (ML) for GitHub Copilot: “LLMs are not trained to reason. They’re not trying to understand science, literature, code, or anything else. They’re simply trained to predict the next token in the text.”

Let’s dive into how LLMs come to do the unexpected, and why. This blog post will provide comprehensive insights into LLMs, including their training methods and ethical considerations. Our goal is to help you gain a better understanding of LLM capabilities and how they’ve learned to master language, seemingly, without reasoning.

What are large language models?

LLMs are AI systems that are trained on massive amounts of text data, allowing them to generate human-like responses and understand natural language in a way that traditional ML models can’t.

“These models use advanced techniques from the field of deep learning, which involves training deep neural networks with many layers to learn complex patterns and relationships,” explains John Berryman, a senior researcher of ML on the GitHub Copilot team.

What sets LLMs apart is their proficiency at generalizing and understanding context. They’re not limited to pre-defined rules or patterns, but instead learn from large amounts of data to develop their own understanding of language. This allows them to generate coherent and contextually appropriate responses to a wide range of prompts and queries.

And while LLMs can be incredibly powerful and flexible tools because of this, the ML methods used to train them, and the quality—or limitations—of their training data, can also lead to occasional lapses in generating accurate, useful, and trustworthy information.

Deep learning

The advent of modern ML practices, such as deep learning, has been a game-changer when it comes to unlocking the potential of LLMs. Unlike the earliest language models that relied on predefined rules and patterns, deep learning allows these models to create natural language outputs in a more human-like way.

“The entire discipline of deep learning and neural networks—which underlies all of this—is ‘how simple can we make the rule and get as close to the behavior of a human brain as possible?’” says Goudarzi.

By using neural networks with many layers, deep learning enables LLMs to analyze and learn complex patterns and relationships in language data. This means that these models can generate coherent and contextually appropriate responses, even in the face of complex sentence structures, idiomatic expressions, and subtle nuances in language.

While the initial pre-training equips LLMs with a broad language understanding, fine-tuning is where they become versatile and adaptable. “When developers want these models to perform specific tasks, they provide task descriptions and examples (few-shot learning) or task descriptions alone (zero-shot learning). The model then fine-tunes its pre-trained weights based on this information,” says Goudarzi. This process helps it adapt to the specific task while retaining the knowledge it gained from its extensive pre-training.

But even with deep learning’s multiple layers and attention mechanisms enabling LLMs to generate human-like text, it can also lead to overgeneralization, where the model produces responses that may not be contextually accurate or up to date.

Why LLMs aren’t always right

There are several factors that shed light on why tools built on LLMs may be inaccurate at times, even while sounding quite convincing.

Limited knowledge and outdated information

LLMs often lack an understanding of the external world or real-time context. They rely solely on the text they’ve been trained on, and they don’t possess an inherent awareness of the world’s current state. “Typically this whole training process takes a long time, and it’s not uncommon for the training data to be two years out of date for any given LLM,” says Albert Ziegler, principal researcher and member of the GitHub Next research and development team.

This limitation means they may generate inaccurate information based on outdated assumptions, since they can’t verify facts or events in real-time. If there have been developments or changes in a particular field or topic after they have been trained, LLMs may not be aware of them and may provide outdated information. This is why it’s still important to fact check any responses you receive from an LLM, regardless of how fact-based it may seem.

Lack of context

One of the primary reasons LLMs sometimes provide incorrect information is the lack of context. These models rely heavily on the information given in the input text, and if the input is ambiguous or lacks detail, the model may make assumptions that can lead to inaccurate responses.

Training data biases and limitations

LLMs are exposed to massive unlabelled data sets of text during pre-training that are diverse and representative of the language the model should understand. Common sources of data include books, articles, websites—even social media posts!

Because of this, they may inadvertently produce responses that reflect these biases or incorrect information present in their training data. This is especially concerning when it comes to sensitive or controversial topics.

“Their biases tend to be worse. And that holds true for machine learning in general, not just for LLMs. What machine learning does is identify patterns, and things like stereotypes can turn into extremely convenient shorthands. They might be patterns that really exist, or in the case of LLMs, patterns that are based on human prejudices that are talked about or implicitly used,” says Ziegler.

If a model is trained on a dataset that contains biased or discriminatory language, it may generate responses that are also biased or discriminatory. This can have real-world implications, such as reinforcing harmful stereotypes or discriminatory practices.

Overconfidence

LLMs don’t have the ability to assess the correctness of the information they generate. Given their deep learning, they often provide responses with a high degree of confidence, prioritizing generating text that appears sensible and flows smoothly—even when the information is incorrect!

Hallucinations

LLMs can sometimes “hallucinate” information due to the way they generate text (via patterns and associations). Sometimes, when they’re faced with incomplete or ambiguous queries, they try to complete them by drawing on these patterns, sometimes generating information that isn’t accurate or factual. Ultimately, hallucinations are not supported by evidence or real-world data.

For example, imagine that you ask ChatGPT about a historical issue in the 20th century. Instead, it describes a meeting between two famous historical figures who never actually met!

In the context of GitHub Copilot, Ziegler explains that “the typical hallucinations we encounter are when GitHub Copilot starts talking about code that’s not even there. Our mitigation is to make it give enough context to every piece of code it talks about that we can check and verify that it actually exists.”

But the GitHub Copilot team is already thinking about how to use hallucinations to their advantage in a “top-down” approach to coding. Imagine that you’re tackling a backlog issue, and you’re looking for GitHub Copilot to give you suggestions. As Johan Rosenkilde, principal researcher for GitHub Next, explains, “ideally, you’d want it to come up with a sub-division of your complex problem delegated to nicely delineated helper functions, and come up with good names for those helpers. And after suggesting code that calls the (still non-existent) helpers, you’d want it to suggest the implementation of them too!”

This approach to hallucination would be like getting the blueprint and the building blocks to solve your coding challenges.

Ethical use and responsible advocacy of LLMs

It’s important to be aware of the ethical considerations that come along with using LLMs. That being said, while LLMs have the potential to generate false information, they’re not intentionally fabricating or deceiving. Instead, these arise from the model’s attempts to generate coherent and contextually relevant text based on the patterns and information it has learned from its training data.

The GitHub Copilot team has developed a few tools to help detect harmful content. Goudarzi says “First, we have a duplicate detection filter, which helps us detect matches between generated code and all open source code that we have access to, filtering such suggestions out. Another tool we use is called Responsible AI (RAI), and it’s a classifier that can filter out abusive words. Finally, we also separately filter out known unsafe patterns.”

Understanding the deep learning processes behind LLMs can help users grasp their limitations—as well as their positive impact. To navigate these effectively, it’s crucial to verify information from reliable sources, provide clear and specific input, and exercise critical thinking when interpreting LLM-generated responses.

As Berryman reminds us, “the engines themselves are amoral. Users can do whatever they want with them and that can run the gamut of moral to immoral, for sure. But by being conscious of these issues and actively working towards ethical practices, we can ensure that LLMs are used in a responsible and beneficial manner.”

Developers, researchers, and scientists continuously work to improve the accuracy and reliability of these models, making them increasingly valuable tools for the future. All of us can advocate for the responsible and ethical use of LLMs. That includes promoting transparency and accountability in the development and deployment of these models, as well as taking steps to mitigate biases and stereotypes in our own corners of the internet.

The post Demystifying LLMs: How they can do things they weren’t trained to do appeared first on The GitHub Blog.

Prompting GitHub Copilot Chat to become your personal AI assistant for accessibility

Post Syndicated from Ed Summers original https://github.blog/2023-10-09-prompting-github-copilot-chat-to-become-your-personal-ai-assistant-for-accessibility/

Large Language Models (LLMs) are trained on vast quantities of data. As a result, they have the capacity to generate a wide range of results. By default, the results from LLMs may not meet your expectations. So, how do you coax an LLM to generate results that are more aligned with your goals? You must use prompt engineering, which is a rapidly evolving art and science of constructing inputs, also known as prompts, that elicit the desired outputs.

For example, GitHub Copilot includes a sophisticated built-in prompt engineering facility that works behind the scenes. It uses contextual information from your code, comments, open tabs within your editor, and other sources to improve results. But wouldn’t it be great to optimize results and ask questions about coding by talking directly to the LLM?

That’s why we created GitHub Copilot Chat. GitHub Copilot Chat complements the code completion capabilities of GitHub Copilot by providing a chat interface directly within your favorite editor. GitHub Copilot Chat has access to all the context previously mentioned and you can also provide additional context directly via prompts within the chat window. Together, the functionalities make GitHub Copilot a personal AI assistant that can help you learn faster and write code that not only meets functional requirements, but also meets non-functional requirements that are table stakes for modern enterprise software such as security, scalability, and accessibility.

In this blog, we’ll focus specifically on the non-functional requirement of accessibility. We’ll provide a sample foundational prompt that can help you learn about accessibility directly within your editor and suggest code that is optimized for better accessibility. We’ll break down the sample prompt to understand its significance. Finally, we’ll share specific examples of accessibility-related questions and results that demonstrate the power of prompting GitHub Copilot Chat to deliver results that improve accessibility. When using GitHub Copilot Chat, we recommend that you think of yourself as a lead developer who is working with a more junior developer (GitHub Copilot Chat). As the lead developer, it is your responsibility to verify information that is provided by GitHub Copilot Chat and ensure it meets all of your requirements.

Foundational accessibility prompt

You can copy this prompt and paste it directly into GitHub Copilot Chat for Visual Studio Code:

“I need to learn about accessibility and need to write code that conforms with the WCAG 2.1 level A and AA success criteria defined at https://www.w3.org/TR/WCAG21/. I want you to be my accessibility coach, a subject-matter expert that makes me think and account for all accessibility requirements and usability enhancements. When you answer questions about accessibility please use reputable sources such as w3.org, webaim.org, developer.mozilla.org, and https://www.ibm.com/able/. When possible, please provide links and references for additional learning. When you suggest code please use semantic HTML, ensure it is operable using the keyboard, follow WCAG 2.1 sufficient techniques, and follow the ARIA Authoring Practices Guide and related design patterns. Do you understand these instructions?”

What does this do?

This prompt can serve as your baseline in your codebase, whether you are just starting a project or in the thick of an extensive project.

The prompt consists of:

  1. Providing solid context and background information to help narrow down the scope of solutions.
  2. Defining GitHub Copilot’s role and setting expectations about what feedback we are looking for.
  3. Being specific in the quality of answers we are looking to reference from reputable sources.
  4. Asking for additional resources and context to learn more and ensure the answers we receive are correct. This helps provide feedback to GitHub Copilot.
  5. Dictating one final set of requirements to even further refine the scope based on the resources we have provided.

Note: At any time you can ask GitHub Copilot if it’s still referencing the foundation prompt you provided and it will inform you of its scope.

Query input: Are you still using the instructions I provided?
GitHub Copilot response: Yes, I am still adhering to the instructions you provided. I will continue to assist you in learning about accessibility and writing code that conforms with the WCAG 2.1 level A and AA success criteria. I will use reputable sources for references and additional learning, and ensure that the code suggestions I provide use semantic HTML, are operable using the keyboard, follow WCAG 2.1 sufficient techniques, and follow the ARIA Authoring Practices Guide and related design patterns.

Examples after the setting the foundation prompt

Note: These prompts were submitted in a brand new workspace that contained no source code or files to reference. Repeating these prompts in your codebase may produce different results as GitHub Copilot can use context provided from open tabs and existing files in the codebase. In addition, please keep in mind that results from LLMs are non-deterministic.

Accessibility testing

Query input: How can I test for web accessibility?
GitHub Copilot response: There are several ways to test for web accessibility:

  1. Manual Testing: This involves navigating your website using only a keyboard, checking color contrast, and resizing text to 200% to ensure readability.
  2. Automated Testing: There are several tools available for automated accessibility testing. Some popular ones include:
    1. WAVE: A free web accessibility evaluation tool provided by WebAIM.
    2. Axe: An accessibility testing toolkit built on a library of accessibility rules.
    3. Lighthouse: An open source, automated tool for improving the quality of web pages. It has audits for performance, accessibility, progressive web apps, SEO, and more.
  3. Screen Reader Testing: This involves testing your website using a screen reader tool. Some popular screen readers include NVDA, JAWS, and VoiceOver.
  4. User Testing: This involves testing your website with people with disabilities. This can provide valuable insights into how accessible your website is in practice.

Remember, no single tool or method can catch all accessibility issues, so a combination of methods is often the best approach.

For more information, you can refer to the following resources:

Tables

Query input: What are some best practices for creating accessible tables in HTML?
GitHub Copilot response: Creating accessible tables in HTML involves several best practices:

  1. Use <th> for table headers: This helps screen readers identify headers. Also, use the scope attribute to specify whether the header is for a row or a column.
    <table>
    <tr>
    <th scope="col">Header 1</th>
    <th scope="col">Header 2</th>
    </tr>
    <tr>
    <td>Data 1</td>
    <td>Data 2</td>
    </tr>
    </table>
    
  2. Provide captions: Use the <caption> element to provide a brief overview of the table. This is especially helpful for people using screen readers.
    <table>
    <caption>Overview of sales</caption>
    <!-- rest of the table -->
    </table>
    

    Use <thead>, <tbody>, and <tfoot>: These elements help to group different sections of the table and can improve accessibility.

    <table>
    <thead> <!-- header group -->
    <tbody> <!-- body group -->
    <tfoot> <!-- footer group -->
    </table>
    
  3. Avoid complex tables: If possible, avoid using tables for complex data structures. If you must, use rowspan and colspan attributes carefully and provide additional information in cell content or with the title attribute.

  4. Ensure readability without styles: The table should be readable and make sense even when styles are turned off.
  5. Use aria-labelledby for complex tables: If a table has multiple levels of headers, use the aria-labelledby attribute to associate data cells with headers.

For more information, you can refer to the WebAIM guide on creating accessible tables.

Forms

Query input: What are some best practices for creating accessible forms in HTML?
GitHub Copilot response: Creating accessible forms in HTML involves several best practices:

  1. Use <label> for form controls: Each form control should have a corresponding <label> element. This helps screen readers identify the purpose of the form control.
    <label for="name">Name:</label>
    <input id="name" name="name" type="text" />
    
  2. Group related form controls: Use the <fieldset> element to group related form controls and <legend> to provide a description for the group.
    <fieldset>
    <legend>Choose your favorite pet:</legend>
    <input type="radio" id="dog" name="pet">
    <label for="dog">Dog</label><br>
    <input type="radio" id="cat" name="pet">
    <label for="cat">Cat</label><br>
    </fieldset>
    
  3. Provide error messages and feedback: If the user makes an error, provide clear and specific feedback. Use the aria-describedby attribute to associate the form control with the error message.
    <input type="text" id="name" name="name" aria-describedby="nameError">
    <span id="nameError">Please enter your name.</span>
    
  4. Use correct input types: Use the correct input type for the form control (for example, email, number, date). This can provide the user with the appropriate keyboard on mobile devices.

  5. Make form controls keyboard accessible: Ensure that all form controls and buttons can be accessed and used with the keyboard.
  6. Use ARIA roles and properties when necessary: If a form control requires more complex interaction, use ARIA roles and properties to provide additional information to screen reader users.

For more information, you can refer to the WebAIM guide on creating accessible forms.

Keyboard support

Query input: What are some best practices for creating proper keyboard support in HTML?
GitHub Copilot response: Creating proper keyboard support in HTML involves several best practices:

  1. Logical Tab Order: Ensure that the tab order of the page follows the visual flow of the content. This can be achieved by structuring your HTML in a logical order. Avoid using positive tabindex values as they can disrupt the natural tab order.
  2. Keyboard Focus Indication: It’s important that users can visually identify which element currently has keyboard focus. This can be achieved using CSS to style the :focus state of interactive elements.
    button:focus, a:focus {
    outline: 2px solid blue;
    }
    
  3. Skip Links: Provide a mechanism to skip to main content or different sections of the page. This can be a link at the top of the page that becomes visible when it receives keyboard focus.
    <a href="#maincontent">Skip to main content</a>
    
  4. Accessible Interactive Elements: Ensure all interactive elements are accessible via keyboard. This includes links, buttons, form controls, and custom interactive widgets. Use semantic HTML elements whenever possible as they have built-in keyboard accessibility.

  5. Keyboard Support for Custom Widgets: If you’re creating custom interactive widgets (like a dropdown menu or modal dialog), you’ll need to provide additional keyboard support. This often involves handling keypress events for keys like Enter, Space, Escape, and the arrow keys. The WAI-ARIA Authoring Practices Guide provides detailed guidance on how to add keyboard support to various types of widgets.
  6. Avoid Keyboard Traps: Ensure that keyboard users can navigate to and from all parts of the page. Avoid situations where keyboard focus can be trapped in a particular page element.

For more information, you can refer to the WebAIM guide on keyboard accessibility.

Aria

Query input: What are some best practices around using proper ARIA roles in HTML?
GitHub Copilot response: ARIA (Accessible Rich Internet Applications) roles can be used to improve accessibility, especially when creating complex interactive elements. Here are some best practices:

  1. Use Semantic HTML First: Before using ARIA, consider whether you can use semantic HTML elements. These elements have built-in accessibility features that often make ARIA unnecessary. For example, use a <button> element instead of a <div> with a role="button".
  2. Don’t Change Native Semantics: Avoid using ARIA to change the semantics of native HTML elements. For example, don’t use role="button" on a link (<a>). Instead, use a <button> element.
  3. Use Appropriate Roles: When you do need to use ARIA, ensure you’re using the appropriate role for the element. The ARIA roles model provides a list of roles and their intended use.
  4. Provide Required States and Properties: Some roles require additional ARIA states or properties. For example, a checkbox requires the aria-checked state.
    <div role="checkbox" aria-checked="false">Check me</div>
    
  5. Use aria-labelledby and aria-describedby: These attributes can be used to provide additional descriptive text for an element.
    <button aria-describedby="info">More Info</button>
    <div id="info">Clicking this button will open more information.</div>
    
  6. Test with Screen Readers: After adding ARIA roles, test your page with a screen reader to ensure it’s providing the intended information.

Remember, ARIA should be used as a last resort when semantic HTML isn’t sufficient. The WAI-ARIA Authoring Practices Guide provides detailed guidance on how to use ARIA correctly.

Analysis

Reviewing the questions we asked GitHub Copilot, it suggested a lot of good information for us to learn more about best accessibility and usability practices. A few responses may be open to interpretation, while other responses lack details or specificity. Some examples include:

  • <tfoot> is an HTML element that calls attention to a set of rows summarizing the columns of the table. Including <tfoot> can help ensure the proper understanding of a table. However, not all tables require such rows–therefore, <tfoot> is not mandatory to have a usable table if the data doesn’t require it.
  • The response for the question about forms stressed the importance of the <label> element, which can help identify different labels for their various inputs. However, that response didn’t include any description about adding “for” attributes with the same value as the <input>’s ID. The response did include “for” attributes in the code suggestion, but an explanation about proper use of the “for” attribute would have been helpful.
  • The response to our question about keyboard accessibility included an explanation about interactive controls and buttons that can be accessed and used with a keyboard. However, it did not include additional details that could benefit accessibility such as ensuring a logical tab order, testing tab order, or avoiding overriding default keyboard accessibility for semantic elements.

If you are ever unsure of a recommendation or wish to know more, ask GitHub Copilot more questions on those areas, ask to provide more references/links, and follow up on the documentation provided. As a developer, it is your responsibility to verify the information you receive, no matter the source.

Conclusion

In our exploration, GitHub Copilot Chat and a well-constructed foundational prompt come together to create a personal AI assistant for accessibility that can improve your understanding of accessibility. We invite you to try the sample prompt and work with a qualified accessibility expert to customize and improve it.

Limitations and considerations

While clever prompts can improve the accessibility of the results from GitHub Copilot Chat, it is not reasonable to expect generative AI tools to deliver perfect answers to your questions or generate code that fully conforms with accessibility standards. When working with GitHub Copilot Chat, we recommend that you think of yourself as a lead developer who is working with a more junior developer. As the lead developer, it is your responsibility to verify information that is provided by GitHub Copilot Chat and ensure it meets all of your requirements. We also recommend that you work with a qualified accessibility expert to review and test suggestions from GitHub Copilot. Finally, we recommend that you ensure that all GitHub Copilot Chat code suggestions go through proper code review, code security, and code quality channels to ensure they meet the standards of your team.

Learn more

The post Prompting GitHub Copilot Chat to become your personal AI assistant for accessibility appeared first on The GitHub Blog.
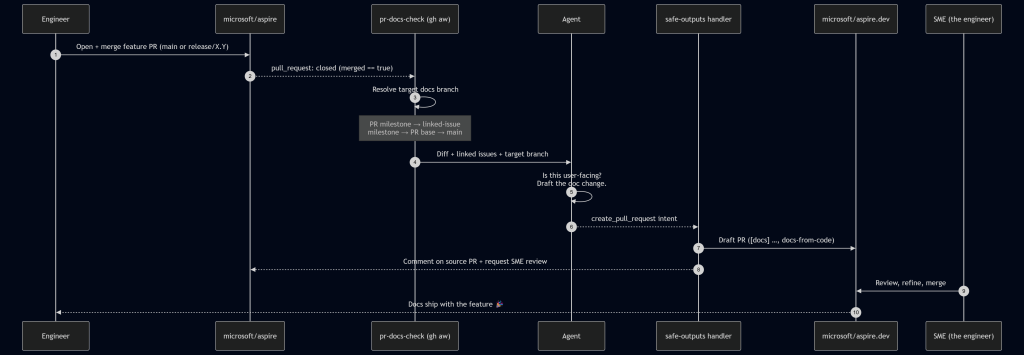
How I used GitHub Copilot Chat to build a ReactJS gallery prototype

Post Syndicated from Senna Parsa original https://github.blog/2023-09-27-how-i-used-github-copilot-chat-to-build-a-reactjs-gallery-prototype/

Ever since we announced GitHub Copilot Chat in March this year, I’ve been thinking a lot about how it’s improving developer happiness and overall satisfaction while coding. Especially for junior developers looking to upskill, or those in the learning phase of diving into a new framework, GitHub Copilot Chat can be such a valuable tool to have in your back pocket.

ICYMI, all GitHub Copilot for Individuals users now have access to GitHub Copilot Chat beta!

The capabilities of GitHub Copilot Chat

With GitHub Copilot Chat, you can now interface with Copilot as a context-aware conversational assistant right in the IDE, allowing you to execute some of the most complex tasks with simple prompts. This goes beyond GitHub Copilot’s original capabilities, which focused on autocompletion and translating natural language comments into code. Now, developers can not only get code suggestions in-line, but they can ask Copilot questions directly, get explanations, offer prompts for code, and more, all while staying in the IDE—and in the flow.

Recently, I was preparing a conference talk and demo about ReactJS, and I had to think a bit about what kind of app I wanted to make with the help of Copilot Chat. Since photography is a hobby of mine, I decided to make a photo gallery of the tulip fields and flower shows around Amsterdam. In the end, I went through a couple different versions of this photo gallery with Copilot Chat. Using a probabilistic model, which is currently based on OpenAI’s GPT-3.5-turbo, it found the best suggestion for me based on how I prompted it, including the question I asked, the code I’d started writing, and other open tabs in my IDE.

Screenshot of GitHub Copilot Chat open in a code editor, on top of a screenshot of a React app in progress. User sennap has asked GitHub Copilot Chat, "Are there any libraries I could use to make this prettier?" Chat has responded with an example of how to use styled-components to style the gallery.

It had been a long time since I had used React, so it probably would’ve taken me a few days of searching and trial and error before coming up with something decent. But with Copilot Chat, each iteration of my photo gallery only took me about 20-30 minutes to go through.

Making prototypes and generating new code

What I most enjoyed about using Copilot Chat to create something new was discovering multiple ways I could implement my component. I didn’t have to leave my IDE and search for advice or a component to use because Copilot would suggest something in real time. If it offered me a suggestion that didn’t work out well, I could give it feedback on why that suggestion didn’t work, which enabled it to offer suggestions that better suited my needs.

Despite working in an unfamiliar framework, Copilot Chat enabled me to immediately start churning out my ideas, which was incredibly satisfying. It was empowering to discover that I can get something done so much faster than what I would have anticipated without any help.

This idea of looking for external help and examples to understand code has been part of the learning process since well before we had AI pair programming tools. I remember when I was first starting in my career and discovering all these new frameworks. I would spend hours, days, weeks doing tutorials and learning about different ways of implementing things. I would learn by copying and pasting things I saw on StackOverflow and seeing how they fit in with the rest of my code (or by chatting with my buddy that I shared a cubicle with at the time).

A lot of the time, these code snippets didn’t even work, but having something to start with really helped with the learning process and that excitement propelled me forward to the next step. This is exactly the magic I felt when using Copilot Chat—while being able to get a contextual suggestion that actually worked and helped me quickly progress to the next thing. Not to mention the amount of time and energy I saved by staying within the context of VS Code instead of searching through websites and other comments online (and avoiding some stress caused by the sentiment of some Stack Overflow comments).

GitHub Copilot Chat in action

When it came time to build my photo gallery, I used Copilot Chat to get suggestions for popular React libraries I could use. There were a few of them that I checked out in separate iterations of the gallery but styled components seems to be the easiest one for me to configure.

I wanted to include a modal as well, so I asked Copilot if the styled components library supported modals. I was really surprised that it knew exactly how to utilize the modal component of the library and how to pass the props in and handle the onClick functionality from the get-go.

In the video, you may notice that it initially gives me a generic suggestion with some boilerplate examples of how to define a modal component and how to reference it from another file. I then asked it to iterate on that suggestion and give me something more specific to how I defined my gallery. This is important because the power of GitHub Copilot is really in the prompt that you provide it: the more fine-tuned the information, the more powerful its suggestions will be. For further reading, check out these prompt tips and tricks for leveraging GitHub Copilot effectively as well as this post on how we compose prompts at GitHub.

Testing out a UI change based on a natural language prompt

When I first tried rendering a modal, that close button was out of view on the top right corner of the screen. This isn’t too difficult to do if you’re regularly developing front-end. Full transparency: I would have needed to Google how to fix this since I just don’t remember how to and CSS is hard! I was shocked that just by asking Copilot Chat to center the “X” button in the modal, it gave me a better suggestion with some new CSS to add display properties to the button that adjust it to my intention. With Copilot Chat, I got the fix I needed without having to leave the IDE or break my flow.

Making accessibility improvements

I have a background in web accessibility and I knew there would be some improvements needed to make the modals interactive with proper focus handling. There are many facets to making a component accessible and it’s important to strategize early on. Best practices include working with accessibility linting tools, and also specialists that can help you balance constraints at the start of the design and development process.

Copilot Chat can be a great addition to those tools by pointing you in the right direction to fixing accessibility issues. In the case of my gallery, the images were not presenting themselves as interactive to keyboard or screen reader users (or, even visually, which goes to show that accessibility makes products better for everyone!). I asked Copilot Chat what it recommended for me to improve the interactivity of the images. The video below illustrates the suggestions it provided around using tabindex, aria attributes, and handling keydown events.

There are, of course, other accessibility considerations to be made here. At some point I decided to make each of the images button elements with a background image, since generally it’s better to use semantic HTML. I then carried on with the rest of my work to manage the focus correctly when opening and closing the modal, as well as making sure only the visible or focused content is presented to a screen reader.

Troubleshooting errors

I was also surprised by Copilot Chat’s ability to help me debug my project whenever I came across an error message. I’d just paste the error into the chat window and GitHub Copilot would offer an explanation for what went wrong and an alternative approach so I could fix the bug quickly and move on.

Writing tests

Knowing that GitHub Copilot can suggest bug fixes, I also wanted to see how it would suggest I write tests for my code. You can ask Copilot Chat for all sorts of test cases, as well as just what kind of testing framework would make the most sense for your application.

In another iteration of my gallery, I used GitHub Copilot to help me render a countdown to the next opening of Tulip season (I went with March 21, 2024, when the tulip festival starts). I decided to make use of the new Copilot Chat slash commands that make it simple to highlight a function and prompt it to help me create some test cases. It suggested using the React testing library for rendering, as well as some methods from Jest to simulate the passage of time and make sure the passing days are represented correctly. From there, I learned about the Jest framework’s Timer Mocks and best practices for testing for fake timers.

Without GitHub Copilot and this new chat feature, navigating a test framework and relying solely on their documentation would have taken even more time.

Summarizing my changes with GitHub Copilot for pull requests

Lastly, I used GitHub Copilot for pull requests to help summarize all the changes I made in a pull request. It gave me a summary of my changes, a walk through of each of the diffs relating to those changes, and even a poem about my application.

Screenshot of an open pull request, which was created by GitHub Copilot Chat, ready to be merged into the tulip gallery repository.

All of this is to show how Copilot Chat and GitHub Copilot for pull requests made the entire coding process much more enjoyable for me while working in an unfamiliar framework—from the initial idea phase to submitting a pull request.

Potential limitations and considerations

While the productivity increases for GitHub Copilot are amazing, there are valid concerns around the quality of code AI paired programming tools suggest and the danger of blindly trusting them. That’s why it’s important to remember that you, the developer, is ultimately the pilot. I think of using GitHub Copilot to be similar to pair programming with another developer: it helps me work faster, but I still need to verify the suggestions it’s giving me to ensure they meet my requirements.

While GitHub Copilot has numerous filters in place to avoid suggestions with vulnerabilities, it’s still important to review and test before deploying. As with any code you did not independently originate, you should ensure code suggestions go through proper code review, code security, and code quality channels to maintain the standards of your team.

The post How I used GitHub Copilot Chat to build a ReactJS gallery prototype appeared first on The GitHub Blog.
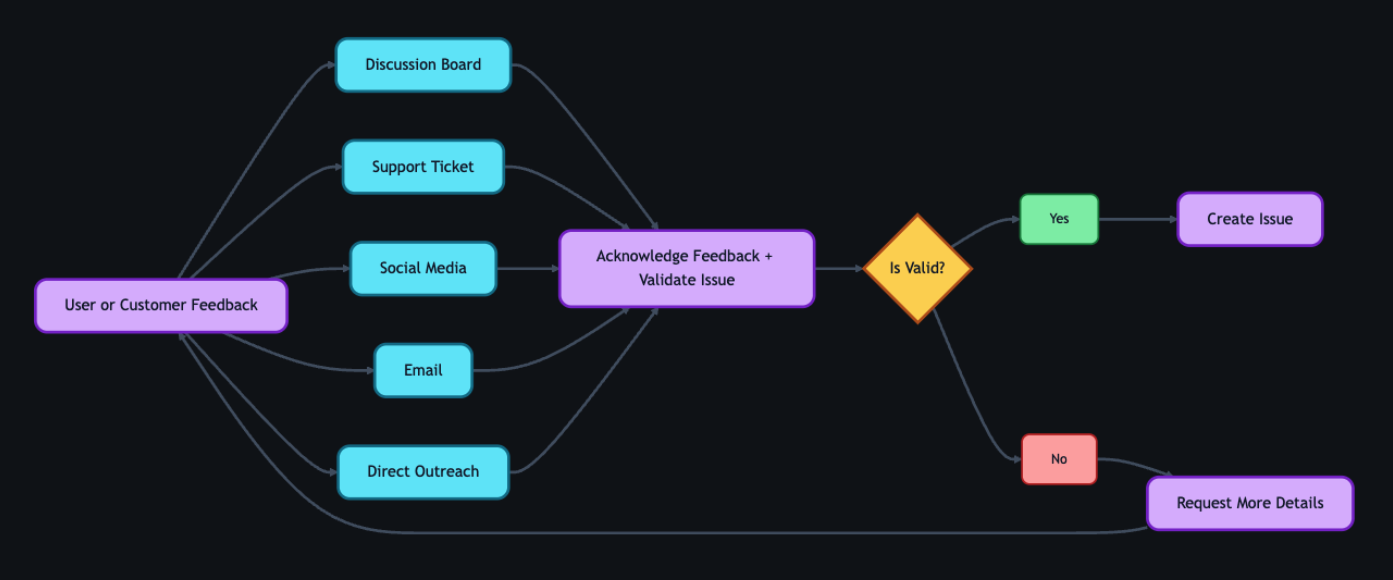
How to build an enterprise LLM application: Lessons from GitHub Copilot

Post Syndicated from Shuyin Zhao original https://github.blog/2023-09-06-how-to-build-an-enterprise-llm-application-lessons-from-github-copilot/

If you want to build and scale an application using a large language model (LLM), this article’s for you.

It took us three years to develop GitHub Copilot before we officially launched it to the general public. To go from idea to production, we followed three stages—find it, nail it, scale it—loosely based on the “Nail It, Then Scale It” framework for entrepreneurial product development.

Here’s how it breaks down:

  • Find it: Identify an impactful problem space for your LLM application
  • Nail it: Create a smooth AI product experience
  • Scale it: Get your LLM application ready and useable for general availability (GA)

Let’s get started.

Find it: Isolate the problem you want to solve

Sometimes the hardest part about creating a solution is scoping down a problem space. The problem should be focused enough to quickly deliver impact, but also big enough that the right solution will wow users. Additionally, you want to find a problem where the use of an LLM is the right solution (and isn’t integrated to just drive product engagement).

  • Get clear on who you want to help. We saw that AI could drive efficiency, so we wanted to prioritize helping developers who were consistently crunched for time, enabling them to write code faster with less context switching.

  • Focus on a single problem, first. Rather than trying to address all developer problems with AI, we focused on one part of the software development lifecycle: coding functions in the IDE. At the time, most AI coding assistants could only complete a single line of code.

  • Balance product ambition with quality. While the GitHub Copilot team initially explored generating entire commits, the state of LLMs couldn’t support that function at a high enough quality at the time. Through additional testing, the team landed on code suggestions at the “whole function” level.

  • Meet people where they are. When it comes to designing products for developers, an LLM app should amplify an existing tool or integrate into an existing workflow. A mantra of the GitHub Copilot team was, “It’s a bug if you have to change the way you code when using GitHub Copilot.” In practice, this means enabling developers to receive code suggestions without changing how they work.

Nail it: Iterate to create a smooth AI product experience

Product development with emerging tech, like generative AI, is often more of a winding path and a linear journey because so much is unknown and rapid advancements in the field can quickly open new doors. Building quick iteration cycles into the product development process allows teams to fail and learn fast. At GitHub, the main mechanism for us to quickly iterate is an A/B experimental platform.

According to Idan Gazit, Senior Director of Research for GitHub Next, “We have to design apps not only for models whose outputs need evaluation by humans, but also for humans who are learning how to interact with AI.

  • Put yourself in users’ shoes. GitHub employees have a culture of putting themselves in the shoes of their end users by “dogfooding” products before—and after—they’re released. In practice, this meant the GitHub Copilot team stood up a simple web interface where it could tinker with foundation models and explore ways to leverage those models in their own developer workflows.

    We quickly found that a web interface was not the right canvas since it meant developers had to switch back and forth between their editor and the web browser. As a result, the team decided to focus on bringing GitHub Copilot to the IDE and making the AI capability modeless—or working in the background.

    The developers on our team also noticed they often referenced multiple open tabs in the IDE while coding. This insight led them to experiment with a technique called neighboring tabs, where GitHub Copilot processes multiple files open in a developer’s IDE instead of just the single one the developer is working on. Neighboring tabs helped to increase the acceptance rates of GitHub Copilot’s suggestions by 5%.

  • Evaluate your testing tools. As our experiment continued, we had to scale our internal testing tools to be more versatile and powerful. While we initially relied on our own tools for testing, we ultimately switched to the Microsoft Experimentation Platform to optimize functionality based on the feedback and interaction at scale.

  • Avoid the sunk cost fallacy. This is when you’re reluctant to abandon a course of action because you’ve heavily invested in it—even when it’s clear switching gears would be more beneficial.

    The GitHub and OpenAI teams initially believed every coding language would require its own fine-tuned AI model. But the field of generative AI was rapidly advancing, and our assumption turned out to be incorrect. In the end, OpenAI’s LLMs significantly improved and one model could handle a wide variety of coding languages and tasks.

  • Make a habit of revisiting old ideas. In a field that’s rapidly advancing, the functions that aren’t feasible with today’s LLMs might be possible with tomorrow’s.

    In the beginning, we explored a chat interface for developers to ask coding questions. However, in early testing, users had much higher expectations for the capabilities and quality of coding suggestions than GitHub Copilot could deliver at the time. As a result, we deprioritized the feature. But as customers became familiar with AI chatbot following the emergence of ChatGPT and LLMs continued to evolve, an iterative chat experience, like GitHub Copilot Chat, became possible.

Scale it: Optimize quality, usability, and responsible use of AI to get to GA

Early feedback and technical previews are key to driving product improvements and getting your application to GA. Below you’ll find the steps we took before launching the GitHub Copilot technical preview, how we managed the technical preview and optimized user feedback, and how we prepared our internal infrastructure to handle demand at scale.

Optimize quality and usability

  • Ensure consistent results. Because LMMs are probabilistic—meaning they don’t always produce the same, predictable outcomes—experimentation with them needs to be statistically based. One solution involves setting up a quality pipeline that addresses this unique challenge of building with LLMs.

    For instance, when the GitHub Copilot team first decided to provide whole function coding suggestions, we also had to ensure output predictability and consistency, where the same prompt and context would produce the same suggestions from the AI model.

    To achieve this, the team applied two strategies: changing the parameters to reduce the randomness of outputs and caching responses. Additionally, using cached responses instead of generating new responses to the same prompt not only reduced variability in suggestions, but it also improved performance.

  • Implement a waitlist for your technical preview. A waitlist allowed the GitHub Copilot team to manage questions, feedback, and comments—and ensure we could address them effectively. This approach also helped ensure we had a diverse set of early adopters across developers of varying experience levels to provide feedback.

  • Take advantage of real user feedback. In one example, developers shared that an update had negatively affected the quality of the model’s coding suggestions. In response, the GitHub Copilot team implemented a new guardrail metric—the percentage of suggestions that are multi-line vs. single line—and tuned the model to ensure customers continued to get high-quality suggestions.

    While the GitHub team actively dogfooded GitHub Copilot to understand what the experience was like for developers, we also benefited from developers outside GitHub adding diverse feedback across real-world use cases. The GitHub Copilot team engaged and interacted with technical preview users early, often, and on the users’ preferred platforms. This allowed us to actively respond to issues and feedback in real time.

  • Commit to iterating as you scale. When GitHub Copilot became generally available, the team not only had to improve the product, but also its infrastructure. When we experimented with and quickly iterated GitHub Copilot, it worked directly with the OpenAI API. As the product grew, we scaled our use of Microsoft Azure’s infrastructure to ensure GitHub Copilot had the quality, reliability, and responsible guardrails of a large-scale, enterprise-grade product.

  • Define the product’s key performance metrics. To optimize GitHub Copilot, we used early developer feedback to identify the right performance metrics, such as code acceptance rate and, eventually, code retention rate (which measures how much of the original code suggestion is kept or edited by a developer).

  • Optimize costs. The team worked to optimize the costs of delivering GitHub Copilot suggestions while balancing developer impact. For instance, before we decided on using ghost text—the gray text that flashes one coding suggestion while you type—the tool would eagerly generate 10 suggestions and display them all at once. This incurred upfront compute costs for suggestions two through 10, when most people choose the first one. But it also created a user experience cost, because those 10 suggestions pulled developers out of their workflow and into an evaluation mindset. “It was like paying to calculate the results that appear on the second page of a search engine—and making that second page grab your attention—even though most folks end up using the top result,” Gazit says.

    Optimizing costs is an ongoing project, and we’re exploring new ideas to reduce costs while improving the user experience.

Optimize responsible use of AI

  • Prioritize security and trust. Feedback during GitHub Copilot’s technical preview reinforced the importance of suggesting code that is secure. In response, the team integrated code security capabilities to filter out suggestions that could contain security vulnerabilities (e.g., SQL injections and hard coded credentials) and used natural language filters from Azure OpenAI Service to filter out offensive content.*

  • Allow your community to help you. At GitHub, we deeply valued our extensive developer community for feedback on our products and collaborating with them to improve our offerings. With GitHub Copilot, our developer community was critical to understanding the potential around AI—and some concerns, too.

    For instance, the developer community was concerned that GitHub Copilot suggestions might match public code. In response, the GitHub Copilot team created a filter to block suggestions matching public source code in GitHub public repositories that were longer than 150 characters.

    Based on community input, the GitHub Copilot team also developed a code reference tool that includes links to public code that may match GitHub Copilot suggestions, so developers can review potential matches (and relevant licensing information), and make informed choices.

Develop a go-to-market strategy

  • Launch your product with product evangelists. Before launching the technical preview of GitHub Copilot in 2021, the team presented the prototype to influential members of the software developer community and GitHub Stars. This allowed us to launch the technical preview with an existing base of support and extend the preview’s reach to a broader range of users.

  • Get your product in front of individual users before going after businesses. The team decided to first sell licenses directly to developers, who would clearly benefit from an AI coding assistant. We paired this approach with a free trial program and monthly pricing, based on user survey findings that individuals prefer a simple and predictable subscription. Gaining traction among individual users helped to build a foundation of support and drive adoption at the enterprise level.

Key takeaways

We’re still in the early days of generative AI, so we’re keeping close tabs on the demand and need for this new technology. While each company and product will need to define its own approach to building an LLM app, here are some key learnings from our product journey with GitHub Copilot:

  • Identify a focused problem and thoughtfully discern an AI’s use cases. This will ensure your app has greater impact and a faster time-to-market.

  • Integrate experimentation and tight feedback loops into the design process. This is especially critical when working with LLMs, where outputs are probabilistic and most end users are just learning how to interact with AI models.

  • As you scale, continue to leverage user feedback and prioritize user needs. Doing so will ensure that your product is built to deliver consistent results and real value.

If you’re looking for a problem to solve with an LLM app, check out our post on how companies are boosting productivity with generative AI. You can also take lessons from how GitHub used GitHub Actions to help an AI nonprofit, Ersilia, disseminate AI models to advance pharmaceutical research in low- and middle-income countries.

The post How to build an enterprise LLM application: Lessons from GitHub Copilot appeared first on The GitHub Blog.
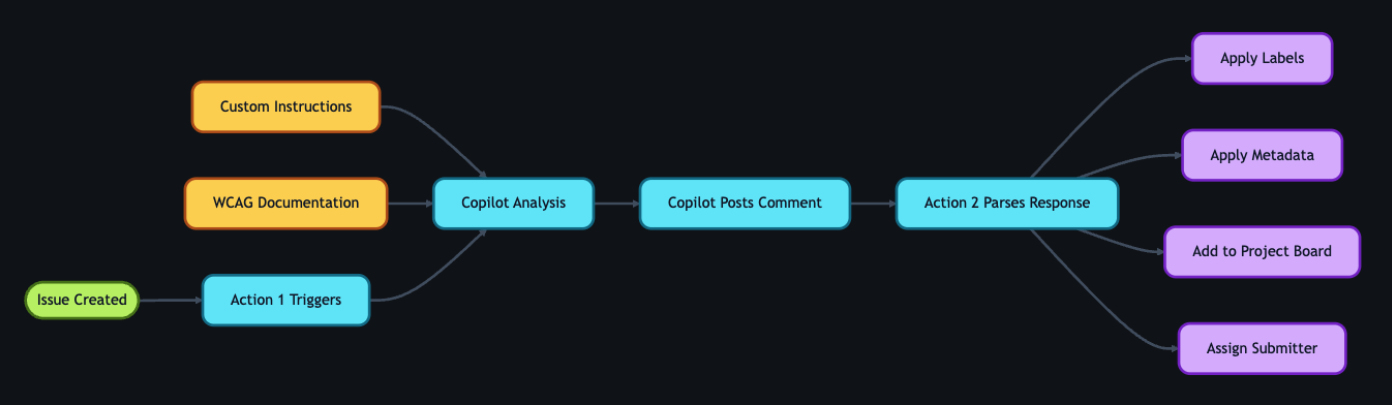
Why Rust is the most admired language among developers

Post Syndicated from Sara Verdi original https://github.blog/2023-08-30-why-rust-is-the-most-admired-language-among-developers/


For the eighth year in a row, Rust has topped the chart as “the most desired programming language” in Stack Overflow’s annual developer survey. And with more than 80% of developers reporting that they’d like to use the language again next year, you have to wonder how a language created less than 20 years ago has stolen the hearts of developers around the world.

In this article, we’ll look at the history of Rust, what it’s commonly used for, why developers love it so much, and some resources to help you start learning one of the top fastest growing languages on GitHub.

So, what is the Rust programming language?

Rust’s print macro displaying the output “Hello, World!”

Originally intended to serve as a safer alternative to C and C++, Rust is a systems programming language that has gained significant popularity among developers thanks to its emphasis on safety, performance, and productivity. Rust is a statically typed language, so variable and expression types are determined and checked at compile time, which helps enhance memory safety and error detection, resulting in more reliable builds.

In 2006, the software developer, Graydon Hoare, started Rust as a personal project while he was working at Mozilla. According to an interview with MIT Technology Review, the inspiration for Rust came from a broken elevator in Hoare’s apartment building. The software for the lift operation system had crashed and Hoare understood that issues like this usually came from problems with how a program uses memory.
Quite often, the software for these types of devices is written in C or C++, but these languages require significant memory management, which can lead to errors that would cause the system to crash. So, Hoare set to work on figuring out how to create a programming language that could be both compact and memory bug-free.

He later showed the project to a manager—which led to Mozilla sponsoring it in 2009 as part of a longer-term effort to incorporate the language into the development of an experimental browser engine. In 2010, Mozilla Research officially announced the Rust project and released the source code to the public as an open-source project. After several years of development, Rust reached a stable and mature state—and in May 2015, Rust 1.0 was released. This milestone signaled that Rust was ready for production and provided a foundation for developers to build upon.

Since the 1.0 release, Rust has exploded in popularity and adoption, with top applications, such as Microsoft Windows, utilizing Rust to rewrite core libraries with its memory-safe code. Outside of the tech giants, Rust also has a vibrant community of developers, or “Rustaceans,” that are dedicated to making the Rust experience an active and collaborative one.

Ferris, an orange cartoon crustacean who is the unofficial mascot of Rust.

Meet Ferris, the unofficial mascot for Rust!

According to a recent survey by SlashData, there are roughly 2.8 million Rust developers worldwide in 2023, a number that has nearly tripled over the past two years. With plenty of active forums, documentation, and a supportive community for developers of all skill levels, it’s perhaps unsurprising that Rust keeps topping the most-desired language lists.

What makes Rust special?

So, what are some of Rust’s key features that make it so attractive to developers?

In simple terms, Rust solves some of developers’ most frustrating memory management problems commonly associated with C and C++, but that’s not its only shining capability. One of GitHub’s staff software engineers, Jason Orendorff, who co-authored a book on programming with Rust, said about the language:

“To me, what’s great about Rust is that it’s both fast AND reliable,” according to Orendorff. “It lets me write multi-headed programs that run on 16 cores and keep them readable, maintainable, and crash-free. It also lets me write very low-level algorithms requiring control over memory layout and pull in a crate that makes HTTPS requests super simple. It’s the combination of these features that makes Rust so unique.”

Building on that, here’s a few more of its well-loved characteristics and features:

  • Concurrency. Rust has built-in support for concurrent programming through its ownership system which enforces strict rules for data access, and its borrowing model, which prevents data races by allowing controlled, simultaneous access. This ensures that multiple threads can work on shared data without introducing memory-related issues.
  • No garbage collection. Unlike some programming languages, Rust does not employ garbage collection. Instead, its ownership and borrowing rules manage memory, which helps empower developers to have precise control over memory allocation and deallocation for efficient resource management.

  • Cargo Package Manager. Rust’s built-in package manager, Cargo, streamlines project management, dependency tracking, and building, which helps contribute to efficient and organized development workflows. But this doesn’t make it clear just how bonkers the Cargo ecosystem is. According to Orendorff, “My team takes advantage of high-quality open source packages for hashing, serialization, multithreading, data structures, compression, and a lot more. These are performance-critical libraries. Without some of these, our project to rethink code search on GitHub wouldn’t have been possible.” And here’s a fun fact: Rust was actually the first systems programming language to have a standard package manager, and, as a result, the Rust ecosystem is incredibly robust.

  • Zero-cost abstractions. This feature allows developers to write high-level code abstractions and features without introducing any runtime performance overhead.

  • Pattern matching. This powerful language feature enables developers to concisely and effectively match complex data structures against specific patterns to extract and handle different cases or scenarios in a clean and readable manner.

  • Type inference. This feature allows Rust’s compiler to automatically detect an expression based on context while you code. “Many programming languages have some type inference,” Orendorff said. “C# and C++ have some, Rust has a little more, and languages like Haskell, Scala, and ML have even more.”

fn main() {
    break rust;
}

Run this code for an inside joke among Rust developers 😆

What is Rust commonly used for?

Thanks to its direct access to both hardware and memory, Rust is well suited for embedded systems and bare-metal development. And since it’s a general purpose language, it can also be used for a variety of applications.

Let’s explore a few key use cases:

Using Rust to build performance-critical backend systems

Performance-critical backend systems are software components or services that handle tasks that require high-speed processing, low-latency responses, and efficient resource utilization—and Rust’s performance, thread safety, and error handling make it an excellent choice for developing these types of systems. In fact, we use Rust to build some of these systems at GitHub. For example, the backend of our code search feature is written in Rust (and you can read more about the development of GitHub’s newest code search with Rust, too).

Using Rust to develop operating systems

Rust was originally created to solve an operating system issue (remember the elevator problem?)—so, unsurprisingly, it’s often used to build operating systems, kernels, device drivers, or other low-level components where control over memory and performance is crucial. Redox, a Unix-like operating system, was written in Rust, which contributes to its most crucial feature: its security. “Fuchsia is another example that was built at Google,” Orendorff said. “If you have a Google Nest smart speaker, it’s likely running Fuchsia.”

Rust for operating system-adjacent code

Rust is also well-suited for writing code that performs tasks that closely interact with the operating system. For example, the Codespaces team at GitHub is leveraging Rust to enhance the speed of starting up the virtual disk within GitHub Codespaces and optimize the utilization of Azure storage. Coursera also employs Rust in its online grading system, as it operates within Docker and needs a language that compiles to machine code with minimal dependencies.

Using Rust for web development

Rust is increasingly being used for web development—especially on the server side. The async programming model and performance characteristics of Rust make it fitting for building high-performance web servers, APIs, and backend services. Plus, there’s been an influx of web frameworks for Rust, like Rocket, that can help folks get started with writing secure web applications. The emergence of these frameworks underscores Rust’s position as a mature language, and also helps increase the support for folks looking to use Rust in front or backend work.

Using Rust for crypto and blockchain development

Rust’s speed, memory management, and security all contribute to its involvement with cryptocurrency and blockchain technologies. For example, Polkadot, which is designed to enable the interoperability and interaction between multiple blockchains to share information and assets in a secure and decentralized manner, utilizes Rust to build its core infrastructure. Polkadot’s runtime logic, which governs the behavior and rules of the blockchain, is also written in Rust. Check out this repository, awesome-blockchain-rust, for some useful components for building your own blockchain applications with Rust.

Using Rust to build CLI tools

Rust’s compilation to efficient machine code and its expressive syntax make it a strong choice for building command line tools and applications. Plus, writing a command line app is a great way to learn and get comfortable with Rust. Take a look at this comprehensive guide on how to build your own CLI application with Rust in 15 minutes!

Learn how open source developers are making the command line more friendly—and more powerful.

Using Rust for embedded systems and IoT development

Rust’s minimal runtime and control over memory layout makes it incredibly useful for developing embedded systems and Internet of Things (IoT) devices. Its ability to prevent memory-related bugs, manage concurrency, and generate small, efficient binaries caters to IoT’s security, real-time, and efficiency needs.

Why developers love Rust

While its user base for Rust isn’t nearly as large as Java or Python, Rust continues to compete with the big hitters in most-admired lists across the internet. There’s even a full website composed of developer’s praises for Rust.

But why exactly is Rust so admired by developers? If you boil it down to just a handful of reasons why developers love Rust so much, they’d have to be the language’s speed, safety, and performance.

Moreover, Rust is continuing to evolve and grow with new frameworks, tools, and resources. You can keep tabs on contributions to the language in the awesome-rust repository, which hosts an impressive list of Rust code and resources.

The bottom line: Admiring Rust isn’t just about adopting a language—it’s embracing a mindset that prioritizes innovation without compromising on the core tenets of stability and security.

How to get started with Rust

We know, there’s plenty of resources to sharpen your Rust skills peppered throughout this article—but we have another pro tip for you: take Rust for a test drive with GitHub Copilot. As your AI-powered pair programmer, GitHub Copilot can help you learn and refine the basics of Rust as you go with tailored code suggestions.

Here’s a developer advocate at GitHub experimenting with Rust for the first time with GitHub Copilot. And to all of our seasoned Rustaceans out there, what do you think? Was the suggestion correct?

If you’re ready to begin your coding journey with Rust, GitHub Copilot can jumpstart your progress—all without the need to study documentation for hours at a time.

The post Why Rust is the most admired language among developers appeared first on The GitHub Blog.