Tag Archives: Tech Lab

Results from the Backblaze Generative AI Media Hackathon

Post Syndicated from Jeronimo De Leon original https://www.backblaze.com/blog/results-from-the-backblaze-generative-ai-media-hackathon/
A graphic with the Backblaze + GMI Cloud logo and the words "Hackathon Winners"

Building generative media applications on object storage: What the strongest projects have in common

Between June 22 and August 3, 2026, 1,314 people entered hundreds of projects into a single brief: build a generative media app on Backblaze B2 object storage, orchestrated through the open-source Genblaze SDK, for a share of a $10,000 prize pool. 

Almost every entry could generate an image, a video, or a soundtrack, and generate it well. What separated the strongest was the layer underneath: what gets written down, what can be proved later, and what happens when a file has to be checked, corrected, or locked against deletion.

Here’s a closer look at the five that went furthest, and the parts worth reusing. Every entry is browsable in the hackathon project gallery.

The brief, and why it was narrow on purpose

The brief was narrower than most hackathons get. Submissions couldn’t just be a working demo and a repo. Devpost required teams to explain, in writing, how their app actually used both Backblaze B2 and Genblaze, and to list every provider and model behind it. Judging ran against four criteria: real-world utility, production readiness, meaningful use of B2, and meaningful use of Genblaze.

That last pair is the constraint that did the work. “Meaningful use” rules out the default architecture, where a team generates an asset, drops the bytes in a bucket, and calls that storage. It forces a decision about what the storage layer is actually for. What follows is written the way a technical and creative director would walk five finished pipelines against exactly that rubric: who each app is actually for, whether it holds up past the demo, and how deep the storage and orchestration choices go.

The two primitives

Backblaze B2 is the ground every one of these apps had to build on: S3-compatible object storage, sized for the sheer volume of generated assets, thumbnails, metadata, and provenance records a media pipeline throws off, free to start with 10GB included.

Genblaze, Backblaze’s open-source orchestration SDK, is what feeds it: a unified Pipeline API spanning providers like OpenAI, Google, Runway, Luma, ElevenLabs, and Stability Audio, plus models served through platforms such as GMI Cloud and NVIDIA NIM, so a team can swap providers without rewriting its orchestration. Every run produces a canonical provenance manifest that can be embedded directly into the media file itself (an .mp4, a .png, an .mp3) and persisted to B2 or any S3-compatible store.

The hackathon also partnered with GMI Cloud, giving teams easy access to open-source generative models for image, video, audio, chat, reasoning, and multimodal work, which is why it turns up as a provider more than once below.

Two primitives, six weeks, hundreds of teams, and five very different examples of rigor.

Winners

1st place · firstframe

https://devpost.com/software/firstframe

github.com/migarci2/firstframe

A review room for AI video ads that doesn’t make you wait for the whole render.

firstframe builds a review room for the marketing and creative teams who commission AI-generated video ads: instead of waiting on a full multi-scene render before anyone can react, it streams the first finished scene as a live HLS playlist the moment it’s ready, appending segments as later scenes land. A reviewer starts giving notes while the ad is still being made, not after.

Every generated scene is scored by an actual vision model before a human ever sees it, so obviously broken output gets caught and retried automatically rather than shipped to a reviewer’s inbox. A failover step swaps in a backup model only on a genuine provider error, never on an ordinary slow response, and once a scene clears review its master file and manifest are locked against deletion for thirty days: a guarantee the code proves by trying to delete a locked file and catching the rejection. Automated QA paired with a tamper-evident record of what was approved is what turns a generation pipeline into something a brand could actually sign off on.

On B2, the bucket’s folder structure doubles as a workflow: a scene moves through incoming, running, provenance, approved, and rejected prefixes as it clears review. Once a scene is approved, its master file and manifest get a real thirty-day write-once hold using B2’s Object Lock in Governance mode, and the code proves that isn’t just decorative by trying to delete a locked object by its version ID and catching the rejection B2 throws back. A reviewer’s application key is scoped to the readFiles capability with a name prefix restricting it to the approved folder alone. Four separate lifecycle rules cover the bucket’s different prefixes: stalled uploads in incoming have their multipart parts cancelled after 24 hours, while rejected, in-progress, and approved objects each age out on their own separate timers. The video segments themselves land in B2 as ffmpeg finishes each one, with the playlist rewritten after every segment, which makes B2 a live broadcast target rather than an archive that fills up after the fact. Reads go out as path-style presigned URLs, working around a known issue where virtual-host-style presigning fails on a private B2 bucket. B2’s own Event Notifications, five signed webhook rules, keep the review room in sync in real time, with a fallback to plain polling if an account’s Event Notifications API isn’t enabled. The app also watches B2’s own transaction cap and backs off to local disk instead of crashing when a call gets rejected for exceeding it.

On Genblaze, generation runs through an AgentLoop scored by a ThresholdEvaluator. The judge is a real vision model, an NVIDIA NIM llama-3.2-90b-vision-instruct instance grading the actual rendered keyframes, not a fixed retry count. Two pipeline branches, audio and video, fan into a single compositor node instead of running as a straight chain, a fallback_models failover is wired in and confirmed to trigger only on a genuine model error rather than a timeout, and every run carries two layers of lineage: a shared run id across scenes and loop iterations, plus a second, custom chain id layered on top of that. The team even embedded the manifest directly inside the delivered MP4, so a separate verification command can re-download and re-hash every asset the file claims exists. Along the way they filed three pull requests and an issue against Genblaze itself.

firstframe puts B2’s feature set to work in front of the reviewer. Object Lock in Governance mode, scoped application keys, lifecycle rules, Event Notifications, and presigned URLs are all load-bearing parts of the review workflow, doing visible work on every scene that moves through it. That’s architecture built to be trusted, not just to work.

2nd place · beavous

https://devpost.com/software/beavous

github.com/AmirmLotfy/beavous

A campaign generator built to double-check its own storage, re-verifying every asset the moment it’s read back.

beavous is built for the marketers and small commerce teams who need a full paid-social campaign out of a single product photo: not one hero image, but four creative concepts, sixteen cropped aspect ratios for every placement, on-label ad copy, and a portrait video reel, packaged as a verified ZIP pulled straight from B2.

A public API hands off to a private worker behind a task queue, and every campaign is namespaced to an organization so tenants stay isolated from each other. When a generation gets rejected, the app doesn’t start over. It chains a correction onto the original attempt, which is closer to how a real creative review actually works than a one-shot retry.

On B2, keys are organized hierarchically by organization and campaign rather than by content hash, because the product is multi-tenant by design. Every upload and download goes through a presigned URL, and the database never stores a raw link, only an object key and a hash. Every time an asset is read back, beavous re-downloads it and re-hashes the bytes independently, rather than trusting a manifest check alone. B2 is treated as the single, sole system of record for every generated asset: a clean, one-source-of-truth design with nothing else to keep in sync.

On Genblaze, three custom providers handle Gemini image generation, Gemini video, and Veo image-to-video, each with its own tiered pricing registered on the model. The more interesting move is a correction chain: when a generation gets rejected, its manifest becomes the parent of the next attempt, an explicit correction lineage most one-shot generation pipelines skip entirely. Prompts are marked private so the text never lands in the public manifest, only a hashed reference to it does, and before any manifest is trusted as a correction parent it gets independently re-verified, not assumed correct just because it was the app’s own write.

beavous’s answer to “do you trust your own storage” is simple: no, never. Check it again, every time. That’s a slower design than trusting your own write, and a more honest one.

3rd place · takegraph

https://devpost.com/software/takegraph

github.com/Enoch208/takegraph

A build system for generative media that can prove its own reuse, recovery, and release integrity, live, against B2.

takegraph is built for teams running a production, not a single generation: the kind of project where a script tweak halfway through shouldn’t mean re-rendering everything from scratch. It treats the whole thing like a software build: a content-addressed dependency graph that, when a spec changes, recomputes fingerprints, rebuilds only what’s actually invalidated, and reuses everything else.

A team can also re-download and re-hash the actual bytes behind any reuse, recovery, or release straight from B2, live, checking integrity themselves instead of trusting a log. That kind of self-auditing separates a pipeline meant to run unattended for months from one built to survive a single demo.

On B2, content-addressed keys use a two-level hash split so directory listings stay fast at scale, B2’s own Event Notifications (HMAC-SHA256-signed webhooks) feed a background process, and a separate reconciler periodically re-checks everything by hand in case a webhook is ever missed, coordinated across workers with a database lock so only one reconciler runs at a time. Unvalidated uploads land in a quarantine prefix backed by a real lifecycle rule that expires it automatically, and a bad key gets rejected outright rather than silently rewritten. Two least-privilege application keys, one for day-to-day work and one for releases, are each scoped to a single bucket, and CORS rules on the work bucket exist specifically to support presigned browser uploads. Verification (re-download, re-hash, prove it) is a feature of the product, not an internal tool.

On Genblaze, takegraph builds a real pipeline around the idea: a dedicated run builder, a content-addressable storage sink, manifests, and observability events tied to every step. The team kept its media-generation side lean, calling straight through the GMI Cloud connector for image and video (one of the hackathon’s partner platforms), and pointed all of its custom engineering at the layer that makes the whole pitch work: the storage and consistency system underneath.

takegraph turns storage verification into the product itself: reuse, recovery, and release integrity are things a user can ask the system to prove, live, rather than take on faith. That’s B2 treated as a system of record in the fullest sense: self-healing, event-driven, and built to survive a missed webhook without anyone noticing.

Special mentions

Ninth

https://devpost.com/software/ninth-mkcgtv

A comic studio with a provider for every model it needed, and a manifest for every frame it drew.

Ninth is built for indie comic authors and motion-comic creators working on a small budget, who revise a scene a dozen times before it’s right and can’t afford to pay for a fresh generation on every pass. Describe a story, and it writes, draws, casts, and stages it panel by panel on an editable timeline, then bakes the result to an MP4.

An edit doesn’t force a re-generation: assets are pulled from a semantic library whenever something close enough already exists, and everything the AI produces (timing, layer position, camera, bubble placement, even the artwork itself) stays editable in place afterward. That reuse-first design is backed by 126 regression tests and a render path that shares its engine with the live editor, so what a creator previews is exactly what gets exported.

Its B2 layer favors verified durability: flat content-addressed keys and a manifest per run, plus real, working endpoints for audit, restore, and backfill that report exactly what’s on B2 versus what’s only on local disk, and rebuild the difference with a SHA-256 check on every recovered file.

On Genblaze, Ninth wrote seven or eight custom providers, covering nearly every model it reached for: Azure’s image model, Gemini’s aspect ratios, Veo keyframes, Gemini’s video interpolation model, ElevenLabs music, and two separate structured-text providers. Each one exists for the same reason: to keep that artifact inside a pipeline and give it a manifest, so a generated frame always carries a record of the run and the prompt that made it.

Ninth’s mention is for discipline: the project that took “every generated frame should be reproducible and recoverable” most literally, and built the tooling to prove it on demand.

Spatialize

https://devpost.com/software/spatialize

A spatial twin that gives a person’s spoken correction the same provenance as a model’s output.

Spatialize is built for venue and accessibility teams who need to rehearse a step-free route through a space before anyone sets foot in it: it turns a flat floor plan into a voice-navigable spatial twin, extracting validated 3D geometry from the plan image, then answering spoken questions with route guidance grounded in that geometry.

Because the underlying use case is safety-adjacent, nothing the model proposes is trusted outright. Every extracted floor plan, and every voice-driven edit to it, has to pass the same deterministic geometry validator before it’s accepted, so a plausible-looking but wrong route never quietly makes it into a rehearsal. When that validator rejects an attempt, it hands back the exact error, and the next attempt corrects specifically that, not a blind retry.

On B2, Spatialize favors resilience: every read goes through a short-lived, presigned link, and if B2 isn’t configured at all, the app quietly falls back to a local, path-safe store instead of failing to boot. It runs two storage paths side by side (its own hierarchical object store for run and scene state, and a separate Genblaze storage sink dedicated to generated-media provenance), keeping application state and generation history cleanly apart.

Under the hood, an agentic loop drives the floor-plan extraction, evaluated at each attempt by that same deterministic validator rather than an LLM’s opinion. Three custom text-to-speech providers form a genuine fallback ladder: a cloud model first, a lightweight third-party API next, and a self-hosted, zero-credential model as the last resort, so a narration request degrades gracefully rather than failing outright. The standout idea: a voice-driven edit to the scene creates a new version tagged as a human change, with the actual transcript kept as evidence, so every point in the final scene traces back to either a model’s manifest or a person’s own words.

Spatialize’s real achievement is conceptual: it gives a spoken correction the same seriousness as a model’s output, tracing every point in the final scene back to either a manifest or a transcript. That’s provenance thinking applied somewhere most generative pipelines never point it.

Same brief, different rigor

Every winning project found its own discipline. What they share is how many different, equally valid kinds of rigor a small team can bring to the same two primitives in six weeks. firstframe made B2’s write-once guarantee visible to a reviewer in real time. beavous made re-verification a habit instead of an afterthought. takegraph made its storage layer heal itself. Ninth made every one of its seven custom providers answerable to the same manifest. Spatialize made a human correction as provable as a model’s.

None of that shows up until a team stops treating storage and orchestration as plumbing and starts treating them as part of the design. firstframe’s win sits at the intersection of both: the same rigor that scores a generated frame with a vision model also locks the finished one against deletion.

What you can build on

Strip the five projects back and the same handful of moves keep appearing, none of which need a hackathon, a large team, or a novel model:

  • Object Lock in Governance mode turns “approved” from a database flag into a storage-level fact, and firstframe proves the hold is real by attempting the delete by version ID and catching the rejection B2 returns.
  • Bucket prefixes (incoming, running, approved, rejected) give you queue semantics without a queue, with a separate lifecycle rule per prefix so stalled multipart uploads and dead rejects expire on their own timers.
  • Re-download and re-hash on read, the way beavous does, because a non-deterministic pipeline produces a lot of near-identical artifacts and hashing is how you know which one you’re holding.
  • Event Notifications as the fast path, a periodic reconciler as the source of truth, so a dropped webhook costs you latency instead of correctness.
  • Content-addressed keys with a two-level hash split keep directory listings fast at scale and make reuse cheap: same fingerprint, same bytes, no second generation to pay for.
  • Application keys scoped one per role, like a reviewer key limited to the readFiles capability with a name prefix restricting it to the approved folder.
  • Correction lineage instead of retries: the rejected run’s manifest becomes the parent of the next attempt and carries the specific error forward. beavous and Spatialize arrived at this independently, which suggests it’s the general shape rather than a niche trick.

All of it is available today. B2 starts free with 10GB, and Object Lock, lifecycle rules, Event Notifications, scoped application keys, and presigned URLs are in the API from day one. Genblaze gives you one Pipeline API across OpenAI, Google, Runway, Luma, ElevenLabs, and Stability Audio, plus models served through GMI Cloud and NVIDIA NIM, and a canonical provenance manifest out of every run that embeds straight into the .mp4, .png, or .mp3 you ship.

A good first project is smaller than any of these five. Take a pipeline you already have, write a manifest for every run, persist it to B2, and add one endpoint that re-downloads and re-hashes an asset to prove the manifest is honest. That’s a weekend of work, and everything above is a variation on it. Genblaze is open source, and three of the pull requests behind firstframe are already in it.

For more ideas, the full project gallery has every entry from the hackathon, and there’s a lot in there beyond the five covered here.

The post Results from the Backblaze Generative AI Media Hackathon appeared first on Backblaze Blog | Cloud Storage & Cloud Backup
Backblaze Generative Media Hackathon: Build with B2, Genblaze, and GMI Cloud

Post Syndicated from Jeronimo De Leon original https://www.backblaze.com/blog/backblaze-generative-media-hackathon-build-with-b2-genblaze-and-gmi-cloud/

The generative AI wave is moving from text into media. ChatGPT taught a generation of developers how to wire up an LLM. The next chapter is harder and more interesting: video, image, audio, and multimodal workflows that combine them. New models for each of these are landing every few weeks, from established labs and from teams nobody had heard of a quarter ago. The quality keeps climbing, and the catalog keeps expanding.

That pace is good news, but it asks more of the apps that depend on it. A pipeline that hard-codes today’s best video model is going to feel dated in a month. The apps that come out ahead will be the ones built on reactive architectures: pipelines that stream progress as events, fan out concurrent work, fall back when a provider stalls, and let you swap in a new model with a single line of code.

That’s where the moat is now. If you’re building an AI media product, the differentiation is in the pipeline: which models you call, in what order, how you fall back when one is slow, how you keep latency tolerable, where the assets land, and how you prove what was generated. The teams winning this space treat the orchestration layer as their core IP. The frontend on top is the easy part.

We’re looking for builds that solve real-world use cases. Show us what becomes possible when the pipeline stops being a bottleneck.

What we’re running

The Backblaze Generative Media Hackathon is an online competition for developers building generative media apps. $10,000 in cash prizes, 10 GB of free Backblaze B2 storage to start with, and GMI Cloud credits for the first 270 eligible participants.

  • Grand Prize: $7,000
  • Second Place: $2,000
  • Third Place: $1,000

Registration and submissions run June 22 through August 3, 2026 (5 pm ET). Winners are announced August 12.

The stack

Backblaze B2, Genblaze, and GMI Cloud are the three pieces of a media pipeline that’s both easy to vibe code and serious enough to take to production.

Backblaze B2 is S3-compatible object storage for the generated assets, the metadata, the provenance manifests, the thumbnails, and the logs. Durable URLs that never expire. Event Notifications fire downstream work without polling. Object Lock makes your provenance records tamper-evident. Lifecycle Rules handle cleanup so intermediate artifacts don’t pile up.

Genblaze is our open-source Python SDK for orchestrating generative media workflows. One Pipeline API spans OpenAI, Google, Runway, Luma, Decart, ElevenLabs, Stability Audio, NVIDIA NIM, GMI Cloud, and others. Every run produces a SHA-256-verified provenance manifest. Swap providers with a one-line change. New models drop every couple of months, and your app doesn’t need a rewrite each time.

GMI Cloud is a unified inference platform for open source AI. Image, video, audio, chat, reasoning, and multimodal models behind a single API key. If you want to try five video models in a weekend, this is the easiest way.

What to build

Anything that turns a generative AI capability into something a real person would actually use. Some directions:

  • AI video generation or editing apps
  • Image generation, remixing, or transformation tools
  • Audio, music, or voice generation workflows
  • Multimodal apps that combine text, image, video, and audio
  • AI media libraries for storing, organizing, and searching generated assets
  • Provenance-aware workflows that track how each piece of media was generated
  • Agentic media pipelines that generate, evaluate, retry, and store outputs
  • Tools for creators, marketers, educators, entertainers, or developers

Judges will weigh real-world utility, production readiness, and how meaningfully your app uses B2 and Genblaze. We’re looking for projects where the pipeline is doing real work. Apps that handle multiple providers, recover from errors, track provenance, and store assets reliably.

How to enter

Visit the hackathon page on Devpost for registration details, eligibility requirements, prizes, submission guidelines, and important dates:

https://www.backblaze-generative-media.devpost.com

Build your generative AI media application using Backblaze B2 and Genblaze, then submit your project before the deadline.

Join the Hackathon

If you want a head start on what a Genblaze + B2 app looks like in code, two reference repos already exist. genblaze-gen-media-multi-provider-sample chains five providers into one prompt-to-MP4 pipeline. genblaze-gmicloud-pipeline is a deep multi-model composition inside one provider.

We’re looking forward to seeing what you build.

The post Backblaze Generative Media Hackathon: Build with B2, Genblaze, and GMI Cloud appeared first on Backblaze Blog | Cloud Storage & Cloud Backup
Introducing Genblaze: A Python SDK for Generative Media Pipelines

Post Syndicated from Jeronimo De Leon original https://www.backblaze.com/blog/introducing-genblaze-a-python-sdk-for-generative-media-pipelines/

Isometric illustration of multiple monitors displaying pixelated data visualizations in a purple, blue, and red color scheme, representing generative AI media pipelines.

A year ago, a good video model was a novelty. Today there are at least six worth using, and most of the teams we talk to are wiring up two or three of them into the same product, alongside image models, voice synthesis, and music generation. The hard question isn’t whether you can generate this kind of media. It’s how to build a pipeline that handles five providers without falling over.

That’s why we built Genblaze, an open-source Python SDK from Backblaze for building generative media pipelines: one API across video, image, and audio providers, swappable models, durable object storage, and a SHA-256-verified provenance manifest on every run.

The pipeline is becoming the moat

Models are commoditizing. New video, image, and audio releases drop every couple of months, and each one tends to be the best at one specific thing and middling at the rest. Nobody we work with is betting on a single provider anymore. They build a portfolio and configure fallbacks.

The pipeline is what stays. It’s where you’ve figured out which model handles which shot type and which voice fits which brand. It’s where retry logic and output guards live, and where your audit trail comes from. That work survives the next model release. The prompts you tuned for last quarter’s hero model don’t.

For a pipeline to actually be durable, though, it has to be reactive. Hard-coding one provider, blocking on every step, and returning a single synchronous result is fine for a demo. In production it ages out in weeks. The pipelines that hold up stream progress as events, fan out concurrent work, handle backpressure from slow providers, and let you add a new model with a one-line change.

That’s what Genblaze is designed to be. One pipeline object, every provider behind the same surface, and a new model is one more .step().

A workflow that uses five providers

Here’s a concrete example: producing a short brand film from a one-paragraph brief.

1. Storyboard frames. Lock the visual direction with Seedream 5.0 Lite or FLUX via GMI Cloud, or Imagen on Google.

2. Animate the approved frame. Kling image-to-video on GMI Cloud, Veo on Google, Runway Gen-4 Turbo, or Luma Ray-2. They’re good at different shot types, so we usually try two and pick. Setting chain=True on the pipeline passes the image from step one into the video step automatically.

3. Score and sound design. Music from Stability AI’s Stable Audio or GMI Cloud’s MiniMax. Ambient effects and voiceover from ElevenLabs. LMNT for low-latency text to speech (TTS) when responsiveness matters.

4. Upscale. There’s an upscale step type built in. Route the rendered video through a Replicate upscaler like Real-ESRGAN to hit delivery resolution.

5. Classify and tag. Use a vision-capable chat() call to tag scenes, run brand safety checks, or generate accessibility metadata. Gemini 2.5, GPT-4o, or Llama 3.2 Vision on GMI Cloud all handle this.

That’s five providers across five different model types, defined in one pipeline. The same retry behavior, fallback chains, and provenance manifest apply to every step.

from genblaze_core import Pipeline, Modality
from genblaze_gmicloud import (
GMICloudImageProvider, GMICloudVideoProvider, GMICloudAudioProvider,
)
from genblaze_replicate import ReplicateProvider
from genblaze_google import GeminiChatProvider

run, manifest = (
Pipeline("brand-film", chain=True)
.step(GMICloudImageProvider(), model="seedream-5.0-lite", prompt="...", modality=Modality.IMAGE)
.step(GMICloudVideoProvider(), model="Kling-Image2Video-V2.1-Master", prompt="...", modality=Modality.VIDEO)
.step(GMICloudAudioProvider(), model="minimax-music-2.5", prompt="...", modality=Modality.AUDIO)
.step(ReplicateProvider(), model="nightmareai/real-esrgan", step_type="upscale")
.step(GeminiChatProvider(), model="gemini-2.5-pro", step_type="classify",
prompt="Tag scenes, return JSON with shots, mood, brand-safety flags.")
.run(sink=storage, timeout=900)
)

Swap any step for a different provider and nothing else in the pipeline has to change.

Provenance

Every run produces a canonical, hash-bound manifest that records the provider, model, prompt, parameters, timestamps, and the URI of every asset it produced. You can embed it directly into the output file (.mp4, .png, .jpg, .webp, .mp3, .wav are all supported by the matching media handler), or persist it as a sidecar JSON.

The hash is deterministic, so anyone downstream can verify the file by calling manifest.verify(). The same manifest is replayable: genblaze replay manifest.json reconstructs the run with the same parameters. And because every manifest carries a parent_run_id, you can trace a v3 video back through v2 and v1, including the fork where you tried Runway instead of Kling.

If you’re building customer-facing pipelines, this is what gets you from “we generated this” to “here’s the proof.”

Storage

Assets and manifests land wherever you want. We default to Backblaze B2, which the SDK wires up with ObjectStorageSink(S3StorageBackend.for_backblaze("my-bucket")) and which gives you durable URLs that don’t expire and don’t need credentials to fetch. The same sink works against any S3-compatible store: AWS S3, Cloudflare R2, MinIO.

A few B2 features pair particularly well with this kind of pipeline.

Event Notifications fire to a webhook, queue, or function endpoint when an asset or manifest lands. That gives you a clean way to kick off downstream encoding, indexing, or moderation without polling.

Object Lock lets you write manifests under a retention policy that nobody (not even the account root) can overwrite until the window expires. Combined with the SHA-256 hash inside the manifest, you’ve got cryptographic integrity and storage-layer immutability.

Lifecycle rules handle the cleanup. Final assets and manifests stay around as long as you want them to. Storyboard iterations, rejected takes, and pre-upscale renders prune themselves on whatever schedule you set.

Partnering with GMI Cloud: a unified AI inference platform for open source

GMI Cloud is a unified AI inference platform for open source. It supports LLM, image, video, and multimodal inference through one consistent API. The catalog covers Seedance, Kling, Veo, and Wan for video; Seedream and FLUX for image; MiniMax for music; ElevenLabs voices; and Llama, DeepSeek, and Qwen for chat and multimodal. One API key reaches all of it.

The genblaze-gmicloud adapter maps GMI’s image, video, audio, and chat endpoints onto the pipeline surface and tracks their catalog as new models ship. The first sample app below uses it heavily.

Two sample apps

genblaze-gmicloud-pipeline goes deep on a single provider. A prompt becomes an anchor image via seedream-5.0-lite. You iterate by passing the current image to flux-kontext-pro for reference-based refinement. Once you approve a frame, the app fans out concurrently to three video models (Kling-Image2Video-V2.1-Master, wan2.6-i2v, pixverse-v5.6-i2v). Manifests get written to B2 next to the assets, and the Genblaze integration sits in a single ~100-line file.

genblaze-gen-media-multi-provider-sample is the workflow above end to end. One sentence becomes a narrated, scored, captioned MP4. gpt-4.1-nano writes the storyboard, Imagen 4 produces the keyframes, Decart Lucy or GMI Cloud Kling animates them, NVIDIA Magpie TTS narrates, GMI Cloud MiniMax scores, and ffmpeg composes the final video. Five providers, one pipeline, every artifact ending up in B2 with a verifiable manifest.

Both are MIT-licensed. Clone, fill in .env, run. GMI Cloud docs can be found here. 

Get started

bash

pip install genblaze

That umbrella installs genblaze-core plus the B2/S3 storage backend, which is enough for a working provenance pipeline. Add genblaze[gmicloud], genblaze, or genblaze[all] to pull in providers.

Where this goes

Most of the interesting work in generative media is happening above the models now, in the pipelines that string them together. Whatever model you’re using today probably won’t be your favorite in six months. The orchestration around it is what lasts.

Genblaze is what we built. It’s MIT-licensed and lives at github.com/backblaze-labs/genblaze.

The post Introducing Genblaze: A Python SDK for Generative Media Pipelines appeared first on Backblaze Blog | Cloud Storage & Cloud Backup
Back Up Your Entire OpenClaw State to Backblaze B2

Post Syndicated from Jeronimo De Leon original https://www.backblaze.com/blog/back-up-your-entire-openclaw-state-to-backblaze-b2/

A decorative image showing a series of 0s and 1s.

There’s a new open-source plugin that snapshots your OpenClaw config, memory, and sessions to B2. It’s designed to be as simple as possible: Three fields to configure. Rollback from chat. Migrate to a new machine in one restart. 

Let’s get into how and why you might want to use it.

OpenClaw keeps everything local. That’s great until it isn’t.

Your config, sessions, memory databases, hooks, cron jobs—everything that makes your OpenClaw instance yours lives on one machine with no built-in redundancy. Compaction can rewrite session transcripts and cause memory loss. A bad config edit or an accidental deletion means rebuilding from scratch: re-onboarding channels, re-pairing devices, re-teaching your agent who you are.

openclaw-b2-backup adds automatic encrypted backups to Backblaze B2 without changing how you use OpenClaw.

Three fields and you’re done

Setup is intentionally minimal:

openclaw plugins install openclaw-b2-backup

Then open ~/.openclaw/openclaw.json and add your B2 credentials to the entry the installer created:

{
"openclaw-b2-backup": {
"enabled": true,
"config": {
"keyId": "004a...",
"applicationKey": "K004...",
"bucket": "my-openclaw-backups"
}
}
}

Restart the gateway, and you’re done. Region is auto-detected from your application key. Encryption is on by default. The first backup runs at midnight, and then daily after that. You can change the schedule to weekly or any cron expression you like.

Free tier friendly: Backblaze B2 includes 10GB of free storage. A typical OpenClaw state directory is 50–500 MB, so even with 10 encrypted snapshots retained, you’ll comfortably stay within the free tier.

Backups that actually happen

The hardest part of any backup system is remembering to run it. This plugin takes care of that with multiple automatic triggers:

  • A daily cron job (configurable) runs a full incremental push at midnight. 
  • Every time you shut down the gateway, a final push runs before exit—so you always have a snapshot of your latest state. 
  • And, before compaction fires (the thing that rewrites your session transcripts and can cause memory loss), the plugin automatically pushes a snapshot. That last one is the one you’ll be most grateful for.

There’s a 5-minute debounce on the compaction trigger, so rapid-fire compactions don’t queue up a dozen pushes.

Rolling back from chat

The plugin registers a b2_rollback tool with your agent, which means you can manage backups conversationally. Just tell your agent:

“Show me my B2 backup snapshots”

And it’ll list all available snapshots with timestamps. To restore one:

“Roll back to the snapshot from before compaction”Before any restore, the plugin automatically creates a safety snapshot of your current state. Safety snapshots are stored separately and never auto-pruned, so you can always recover from a bad rollback. It’s an undo for your undo.

Moving to a new machine

This was one of the most requested use cases: Getting your entire OpenClaw setup onto a new machine without manually copying files and hoping you got everything.

Install the plugin on your new machine, add the same B2 credentials, and restart. The plugin detects the empty state directory, finds your existing snapshots in B2, and automatically restores the latest one. Same memory, same sessions, same config, same personality. No manual file copying.

openclaw plugins install openclaw-b2-backup
# Add your B2 config to openclaw.json
openclaw gateway restart
# Plugin detects empty state + existing snapshots → auto-restores latest

Security by default

Everything is AES-256-GCM encrypted before it leaves your machine. Each file gets a random salt and IV, so identical files produce different ciphertext. The encryption key is derived from your B2 application key via scrypt—no separate key to manage or lose.

Manifests (which contain only file paths and SHA-256 hashes) stay unencrypted so incremental diffing works regardless of encryption. Credentials and auth profiles are excluded from sync by design—secrets stay per-machine, and you re-auth on new machines.

Best practice: Use a B2 application key scoped to a single bucket for least-privilege access. The plugin works perfectly with bucket-scoped keys—region is auto-detected from the authorize response.

Zero external dependencies

The plugin has no external runtime dependencies beyond croner for scheduling. The B2 client is a hand-rolled AWS Signature V4 implementation using only node:crypto. No AWS SDK, no S3 library, no heavyweight dependencies to audit or keep updated.

It runs entirely inside the gateway process—no external scripts, no separate cron daemon, no stopping the gateway to take backups.

Get started

The plugin is open source (under the MIT license) and available now:

openclaw plugins install openclaw-b2-backup

Source code and full documentation: github.com/backblaze-b2-samples/openclaw-b2-sync-backup

npm package: npmjs.com/package/openclaw-b2-backup

If you run into issues or have feature requests, open an issue on GitHub. And if this plugin saves you from a rebuild, we’d love to hear about it.

The post Back Up Your Entire OpenClaw State to Backblaze B2 appeared first on Backblaze Blog | Cloud Storage & Cloud Backup
Introducing the Backblaze Flamethrower Startup Program

Post Syndicated from Stephanie Doyle original https://www.backblaze.com/blog/introducing-the-backblaze-flamethrower-startup-program/

A decorative image showing cogs and cubes with digital lines.

The Backblaze Flameflower Startup Program is here, and it’s built by people who’ve been burned before (and that’s a good thing for you). 

Startups don’t fail because they pick the wrong cloud storage provider.

They fail because everything else is already hard enough, and infrastructure quietly becomes the thing that slows them down, surprises them, or blows up their budget at exactly the wrong moment.

That’s why we’re launching Flamethrower, the new startup program from Backblaze.

It’s not a gimmick. It’s not a lead trap. And it definitely doesn’t bring the “here’s some credits, good luck” energy.

Flamethrower exists for one simple reason: Founders deserve storage infrastructure that helps them move faster, not learn expensive lessons the hard way.

Why Flamethrower exists

Why Flamethrower? 

Startups don’t need more friction, they need a way through it. Metaphor-wise, flames have always been a part of Backblaze’s DNA, and we want this program to speak to the strongest parts of that fire: speed when you need it, reliability when it counts, and power to scale without drama. 

Flamethrower takes these ideas and applies it directly to startups, burning away the biggest blockers between you and your next milestone.

I’ve spent most of my career in and around startups, as a founder, an operator, a partner, a mentor, and occasionally as the person explaining to a CFO why last month’s cloud bill looked like a typo.

I’ve seen the pattern repeat over and over:

  • Early teams optimize for speed (correct)
  • Infrastructure decisions get made quickly (also correct)
  • Those decisions quietly become very sticky
  • And later… someone realizes storage costs are now a board-level discussion

Flamethrower is designed to meet teams before that moment, making your architecture deliberate, not accidental.

Not with abstract promises, but with:

  • Real infrastructure used in real production environments
  • Credits that actually help you get to product-market fit
  • And access to real, live humans who understand what it’s like to build under pressure

This program was built by founders, for founders, including a lot of hard-earned lessons from what doesn’t work.

What makes Flamethrower different

There are plenty of startup programs out there. Many are well-intentioned. Some are very good at marketing. A few are genuinely useful.

Flamethrower is focused on a few things we think matter more than buzzwords:

Human interaction (Yes, really)

Your application is reviewed by real people. Your emails are read by real people.

And if you want to talk to someone, you’ll talk to someone who understands startups, architectures, and workflows, not a generic support queue.

Infrastructure that scales with you

Backblaze B2 is simple, predictable, and S3 compatible. Teams use it for:

In other words: the boring stuff that absolutely has to work.

A program that respects your time

No mandatory demos. No surprise sales motions. No pressure to “convert” before you’re ready.

If Flamethrower helps you build faster—great.

If it doesn’t—that’s okay too, we’ll handle the boring bits until your rocket ship takes off.

Why Backblaze

Backblaze has always had a bit of a different personality.

We believe:

  • Pricing should be understandable
  • Infrastructure should behave predictably
  • Documentation should be written by people who actually use the product
  • And success shouldn’t be punished with surprise bills

That mindset is exactly why Flamethrower fits here.

This isn’t a side project. It’s an extension of how Backblaze already works with developers and builders, just with a little more gas on the fire (if you will).

A bit about me

If we haven’t met yet: I’m James, and I lead Startups and Developer Relations at Backblaze.

I’ve spent years building and running startup programs, developer ecosystems, partnerships, and learning, sometimes painfully, what not to do. I’ve been on the receiving end of “exciting programs” that turned out to be mostly slide decks.

Flamethrower is my attempt (with a very smart team) to build the kind of program I wish existed when I was earlier in my career: practical, honest, and actually useful.

No heroics. No silver bullets. Just support where it counts.

What happens next

The Flamethrower Program is officially live!

If you’re:

  • A founder building something data-heavy
  • An early team thinking about long-term infrastructure
  • Or someone who just wants storage to be the least cumbersome (and most strategic) part of their stack

We’d love to hear from you.

  • Learn more and apply to Flamethrower
  • Or just explore Backblaze on your own terms.
  • Sign up for the Developer newsletter to stay up-to-date with news about the platform and other peoples’ cool projects. 

And if nothing else, thanks for building things. The world needs more people who do.

The post Introducing the Backblaze Flamethrower Startup Program appeared first on Backblaze Blog | Cloud Storage & Cloud Backup
A Deeper Look at S3 Compatible Lifecycle Rules in Backblaze B2

Post Syndicated from Bala Krishna Gangisetty original https://www.backblaze.com/blog/a-deeper-look-at-s3-compatible-lifecycle-rules-in-backblaze-b2/

A decorative image showing a pattern of diamonds on a gradient background.

As data footprints swell and multi-cloud strategies become the norm, the complexity of managing object lifecycles—from initial creation to eventual archival or deletion—can introduce significant risk and operational overhead. To help our customers solve for this, we recently announced support for lifecycle rules through S3-compatible APIs.

While the previous post focused on what the feature enables and why it matters, this follow-up will look at how lifecycle rules work at a deeper level and what to keep in mind when using them in production.

Why S3 compatible lifecycle rules matter

Let’s quickly refresh your memory about why this feature matters. Many customers already rely on lifecycle rules in Backblaze B2 to manage storage costs and data retention. These rules automate actions like deleting old objects, hiding previous versions, or cleaning up incomplete multipart uploads.

By adding S3 compatible support for lifecycle rules in Backblaze B2, it allows you:

  • Lift and shift migrations from AWS S3 to Backblaze B2
  • Reuse of existing tools, xml configurations, scripts, applications & infrastructure as code
  • Predictable behavior across environments as part of multi-cloud strategy

API surface area and XML structure

Lifecycle rules are managed using three APIs:

  • PutBucketLifecycleConfiguration
  • GetBucketLifecycleConfiguration
  • DeleteBucketLifecycleConfiguration

These APIs accept and return XML documents that follow the AWS S3 lifecycle configuration format. From a client perspective, this behaves the same way it does on S3, including rule IDs, status flags, filters, and actions. 

Example put lifecycle request

Below is a simple example that hides objects under the logs/ prefix after 30 days.

PUT /?lifecycle HTTP/1.1
Host: my-bucket.s3.us-west-004.backblazeb2.com
Content-Type: application/xml
<LifecycleConfiguration>
<Rule>
<ID>deleteOldLogs</ID>
<Status>Enabled</Status>
<Filter>
<Prefix>logs/</Prefix>
</Filter>
<Expiration>
<Days>30</Days>
</Expiration>
</Rule>
 <Rule>
<ID>deleteOldLogs_marker</ID>
<Status>Enabled</Status>
<Filter>
<Prefix>logs/</Prefix>
</Filter>
<Expiration>
<ExpiredObjectDeleteMarker>true</ExpiredObjectDeleteMarker>
</Expiration>
</Rule>
</LifecycleConfiguration>

If the XML validates successfully, B2 stores this configuration and returns a 200 OK response.

Example get lifecycle response

GET /?lifecycle HTTP/1.1
Host: my-bucket.s3.us-west-004.backblazeb2.com
<LifecycleConfiguration>
<Rule>
<ID>deleteOldLogs</ID>
<Status>Enabled</Status>
<Filter>
<Prefix>logs/</Prefix>
</Filter>
<Expiration>
<Days>30</Days>
</Expiration>
</Rule>
</LifecycleConfiguration>

The response mirrors the original configuration, allowing tools like Terraform or AWS CLI to reconcile state.

Mapping from S3 rules to B2 rules

Backblaze B2 already supported lifecycle rules through the B2 Native API. The S3 compatible lifecycle implementation builds on this foundation.

Here is how the mapping works at a high level:

  • Each S3 lifecycle rule is converted into one or more internal B2 lifecycle rules.
  • Prefix filters in S3 map directly to B2 file name prefixes.
  • Expiration actions translate into B2 hide or delete operations.

This approach allows us to reuse the same lifecycle execution engine while exposing a familiar S3 interface.

Conceptually, the flow looks like this:

S3 XML lifecycle rule
|
v
XML validation
|
v
S3 rule compilation
|
v
B2 lifecycle rule objects
|
v
Lifecycle execution engine

Expiration behavior

Lifecycle rules can target both current and non current versions.

Some important details:

  • Expiring the current version results in a hide marker being created, matching S3 behavior.
  • Non current version expiration deletes older file versions after the configured number of days.
  • B2 keeps the same guarantees around version ordering and visibility that exist in the native API.
  • To remove abandoned hidemarkers by default, an ExpiredObjectDeleteMarker rule for expiration by days is a must.
  • The ExpiredObjectDeleteMarker rule ID is derived from the expiration by days rule ID with a “_marker” suffix.

Understanding this behavior is important if you rely on object versioning for recovery or audit purposes.

Here is an example to remove older versions of objects with prefix data/ that are hidden for more than 90 days.

<Rule>
<ID>delete-old-versions</ID>
<Status>Enabled</Status>
<Filter>
<Prefix>data/</Prefix>
</Filter>
<NoncurrentVersionExpiration>
<NoncurrentDays>90</NoncurrentDays>
</NoncurrentVersionExpiration>
</Rule>

How this behaves internally

At evaluation time, B2 walks object versions in order and applies rules like this:

Pseudo code:

for each object in bucket:
for each version of object with data prefix:
if version is non current:
if age_in_days >= NoncurrentDays:
delete version

For current versions, expiration works differently.

Expiring the current version

When a lifecycle rule expires the current version, B2 creates a hide marker instead of deleting data immediately.

This matches S3 semantics and preserves version history.

current version expired
|
v
hide marker created
|
v
current version becomes non current

Overlapping and nested prefix rules

Backblaze B2 supports multiple lifecycle rules on the same bucket, including overlapping and nested prefixes.

For example, you might configure:

  • A general rule for logs/ that deletes objects after 365 days
  • A more specific rule for logs/audit/ that deletes objects after 90 days

When rules overlap, the configuration with lowest value is applied to save cost to you. This mirrors S3 behavior and allows fine grained control without duplicating buckets.

Matching logic:

object path: logs/audit/2024/01/file.json

matching rules:
- logs/
- logs/audit/

selected rule:
- logs/audit/ because it has lowest value, 90 days

Multipart upload cleanup

Lifecycle rules can also be used to abort incomplete multipart uploads if not completed in a certain number of days. This is implemented by tracking the initiation time of multipart uploads and periodically removing uploads that exceed the configured threshold. This helps prevent abandoned uploads from consuming storage indefinitely. 

Below is an example rule to delete multipart uploads that are not completed after seven days after starting the upload process.

<Rule>
<ID>abort-multipart</ID>
<Status>Enabled</Status>
<AbortIncompleteMultipartUpload>
<DaysAfterInitiation>7</DaysAfterInitiation>
</AbortIncompleteMultipartUpload>
</Rule>

Internal execution model

Multipart uploads are tracked with their initiation timestamp.

Pseudo code:

for each multipart_upload:
if now - initiation_time >= DaysAfterInitiation:
abort upload
delete uploaded parts

Lifecycle execution model

Lifecycle rules are not executed in real time. Instead, they are evaluated by background processes that scan eligible objects and apply actions asynchronously.

Important characteristics:

  • Rules are not evaluated in real time
  • Execution is eventually consistent
  • Large buckets may take multiple passes to fully apply changes

This design allows lifecycle processing to scale across billions of objects efficiently without impacting foreground operations.

High level execution flow:

scan bucket periodically
|
v
identify eligible objects
|
v
apply lifecycle actions (hide and/or delete)
|
v
record progress and continue

Error handling and validation

Lifecycle XML is validated using S3 compatible rules:

  • Invalid combinations of actions are rejected
  • Missing required fields return errors
  • Unsupported actions return descriptive failures

While error messages may differ slightly from AWS, the validation logic follows the same constraints.

Compatibility considerations

While the goal is strong S3 compatibility, there are still some things to keep in mind:

  • Not all S3 lifecycle actions are supported yet
  • XML validation follows S3 rules, but error messages may differ slightly
  • The underlying storage model of B2 can affect timing and visibility

We recommend testing lifecycle rules in a non production bucket before rolling them out broadly.

Final thoughts

Adding S3 compatible support for lifecycle rules on Backblaze B2 was all about making migrations simpler and letting customers reuse existing automation with confidence. It behaves the way you expect while benefiting from B2’s internal scalability. 

If you already manage lifecycle rules using S3 APIs, those same configurations can now run on Backblaze B2 with minimal or no changes.

The post A Deeper Look at S3 Compatible Lifecycle Rules in Backblaze B2 appeared first on Backblaze Blog | Cloud Storage & Cloud Backup
Network Stats for Q4 2025: Neocloud Traffic Trends

Post Syndicated from Brent Nowak original https://www.backblaze.com/blog/network-stats-for-q4-2025-neocloud-traffic-trends/

A decorative image with the text Q4 2025 Network Stats.

Welcome to our second quarterly Network Stats report covering Q4 of 2025. Along with Drive Stats and Performance Stats, Network Stats pulls back the curtain on real-world infrastructure data, particularly how network-level analytics reflect emerging AI industry trends and usage patterns.

Get more Network Stats (and the details of the dataset)

If you are curious about what metrics we’re recording and how we classify data in this series, check out the details outlined in our Q3 2025 Network Stats  report.

One of the roles of the Network Engineering (NetEng) team at Backblaze is to monitor how traffic moves into, out of, and across our platform—not just day-to-day, but over time as customer behavior and industry dynamics evolve. Right now, few forces are reshaping networks faster than AI. 

With the launch of B2 Overdrive in April 2025, we built a direct, high-performance path between our storage layers and neoclouds where processing, inference, and modeling take place. It has given us a front-row seat to the impact of AI and how network behavior is changing with it. This quarter, in addition to our regular data analysis, I’ll walk through where AI-driven traffic is concentrated, how ingress and egress patterns showed up, and what the findings say about where AI infrastructure might be headed next. 

Continue the conversation

Join us live for the Q4 2025 Network Stats webinar Wednesday, February 4, 2025 at 10:00 a.m. PT / 1:00 p.m. ET. We’ll explore where AI traffic concentrates, how high-magnitude data flows behave, and what early indicators suggest about the future of AI-native infrastructure design.

Can’t make it live, or reading this article after-the-fact? Sign up anyway and catch the recording on demand.

Get Inside Real AI Network Flows

Brave new market

AI workflows don’t just need a place to store data, they need to be able to move it quickly, easily, and nearly constantly for short bursts. Large, multi-petabyte datasets are ingested, transformed, exported for training, pulled back for evaluation, and periodically refreshed as models evolve.  

Backblaze plays a key role at both ends of that lifecycle. We serve as a durable storage layer for the initial data ingestion, and as the high-throughput source feeding model training, evaluation, and validation to whatever best neocloud is suitable at the moment. Once that model has been trained, it needs to be stored, served, and periodically retrained, where we serve as the storage medium.

This quarter, we saw a large amount of traffic between Backblaze, neoclouds, and traditional hyperscalers for processing concentrated across the months of June to November. This reflects large-scale ingestion events followed by intensive data manipulation and model-related egress. 

From a network perspective, this represents a meaningful shift from diffuse, internet-style traffic patterns to large, high-bandwidth flows between a smaller set of endpoints typical of AI-centric infrastructure.

The neocloud slice

The defining theme of the quarter is “new:” new AI-oriented workflows, new traffic patterns, and leading indicators of new infrastructure trends. 

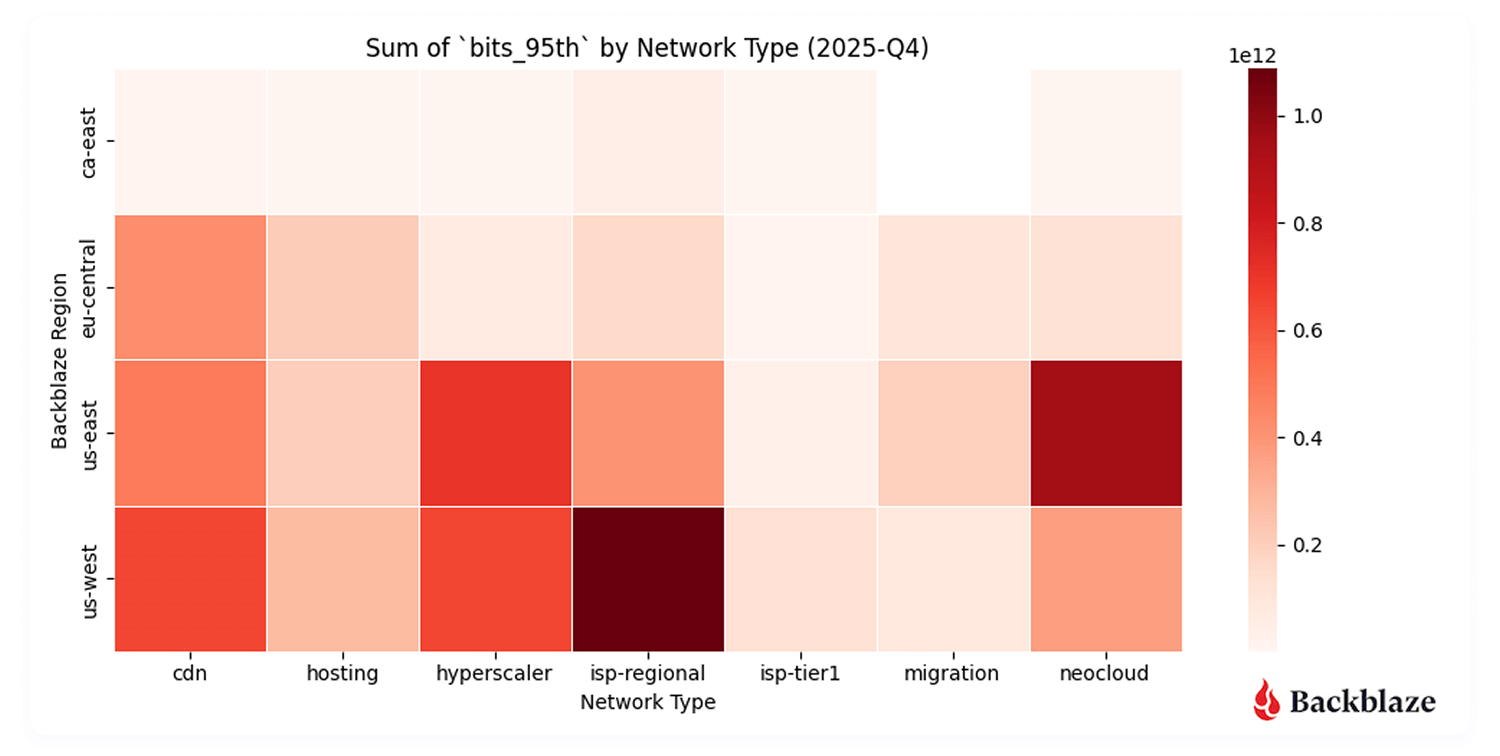
The stacked area graph below shows total traffic by network type over time. While content delivery network (CDN), hosting, and internet service provider (ISP) traffic stayed largely within historical norms reflecting steady-state usage patterns like content delivery, web hosting, and traditional backup workflows, two slices stand out:

  • Migration traffic: We saw a notable increase in migration traffic from August through October.  This classification reflects an influx of data into our network over fiber connections we have in the data centers to cost effectively migrate large amounts of data over private links, not using the public Internet.
  • Neocloud traffic: We saw a sharp increase in July through November, peaking in October.

What do we think is happening? Taken together, these patterns suggest a familiar AI lifecycle:  large datasets consisting of assets like images, videos, and metadata are ingested and consolidated then exported for training and experimentation. Now, those assets can be periodically updated as new assets are added and generated models and stored. We see that heading into the new year, the overall baseline has increased indicating a new normal.

Quick terminology refresher

  • Regions
    • US-West: Our largest and longest-running region
    • US-East: Region with the most observed proximity to neocloud infrastructure
    • CA-East: Our newest region in Canada. 
  • Network Types
    • CDN: Networks that use Backblaze as an origin store for content delivery 
    • Hosting: Traditional hosting providers that runs workloads like physical or virtual servers for web, database, or application tasks
    • Hyperscaler: Large, traditional cloud providers
    • ISP Regional: Local or regional ISPs, think of these as the “last mile” paths as these networks are very close to customer equipment and efficient 
    • ISP Tier1: National or international ISPs that carry our traffic long distances
    • Neocloud: AI -focused compute networks
    • Migration: Network links that we use for large-scale data onboarding

Heatmaps: Where AI traffic concentrates

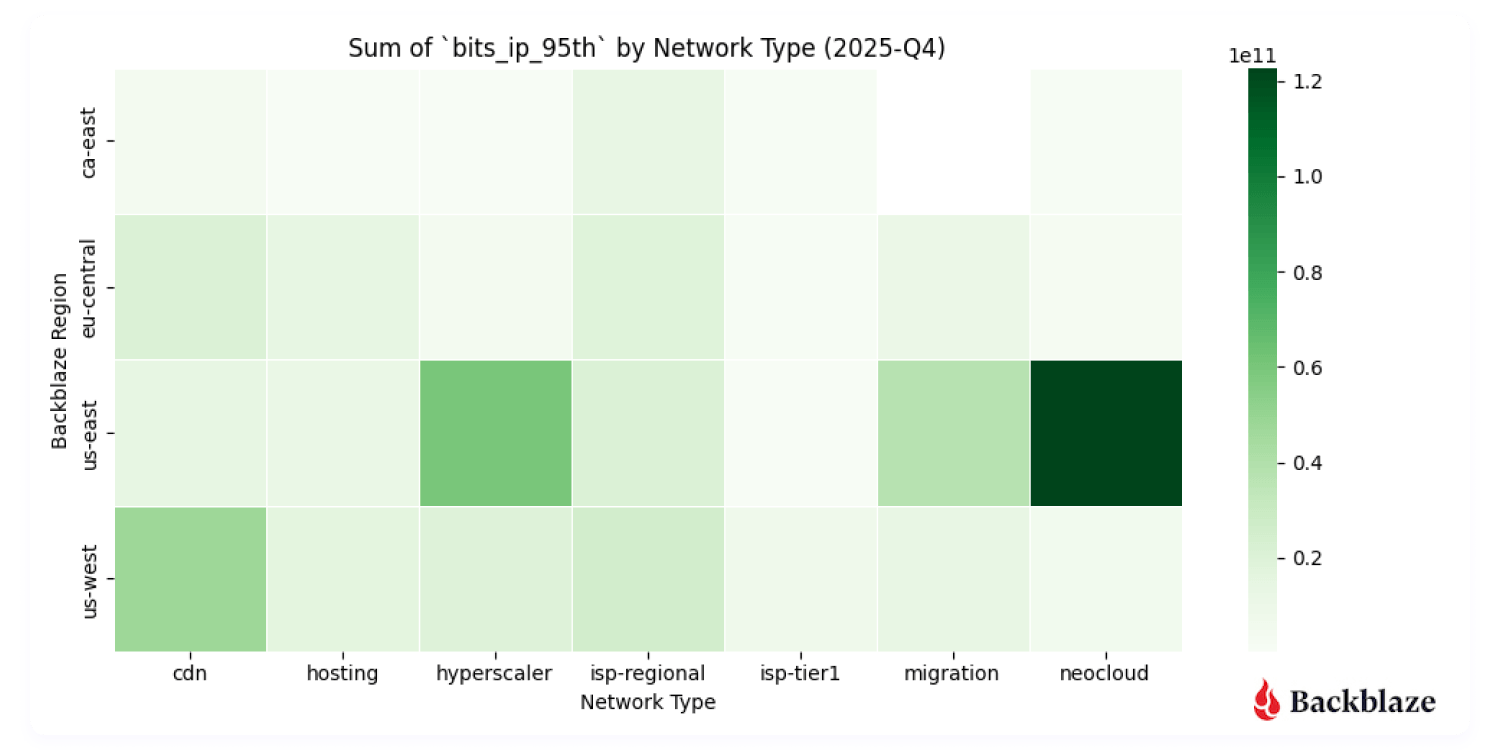
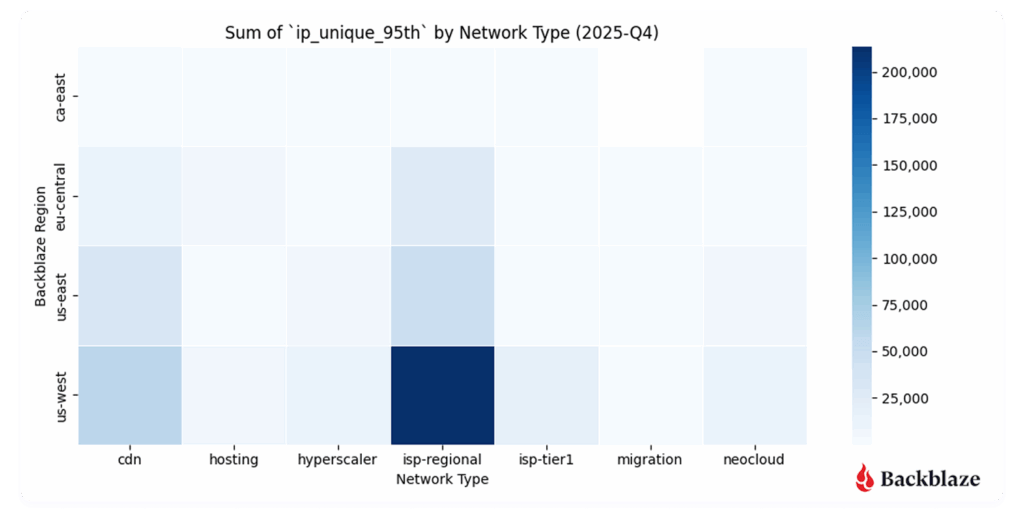
To better understand where AI activity is happening, we thought it would be interesting to isolate the different Backblaze regions and to view concentrations of metrics visualized through heatmaps. We’re going to look at the following three dimensions: 

  1. Total traffic volume: Where did we send and receive the most traffic? 
  2. Magnitude: Where were the data transfers with the most bits per unique IP address?
  3. Uniqueness: What does the number of distinct IP addresses look like? 

Heatmap #1: Where did we send and receive the most traffic?

Unsurprisingly, US-West ↔ ISP-Regional traffic dominates in total traffic volume. This region has the largest data center footprint behind it, with connectivity to internet exchanges (IX) such as Equinix-IX that were brought online in 2023. Internet exchanges bring us closer to consumer networks, where we can deliver traffic with lower latency.

More interesting, however, is the US-East ↔ neocloud concentration. Our flow data shows neocloud activity clustering in regions including Chicago, Dallas-Houston, Denver, New York, Northern Virginia (Reston/Ashburn corridor), and Atlanta—skewed more towards the East Coast where there’s dense AI compute availability. 

From a performance standpoint, this makes sense. It’s important to keep latency (the time between the source and destination) lower to achieve consistent high bandwidth rates for AI data transfers. For now, that gravity is pulling activity towards the East coast. 

Will neocloud traffic concentrations shift over time? Since this is our first quarter with a full dataset, it’s a bit early to draw long-term conclusions. But this is exactly the kind of trend we’ll be tracking. Stay tuned for future Network Stats reports.

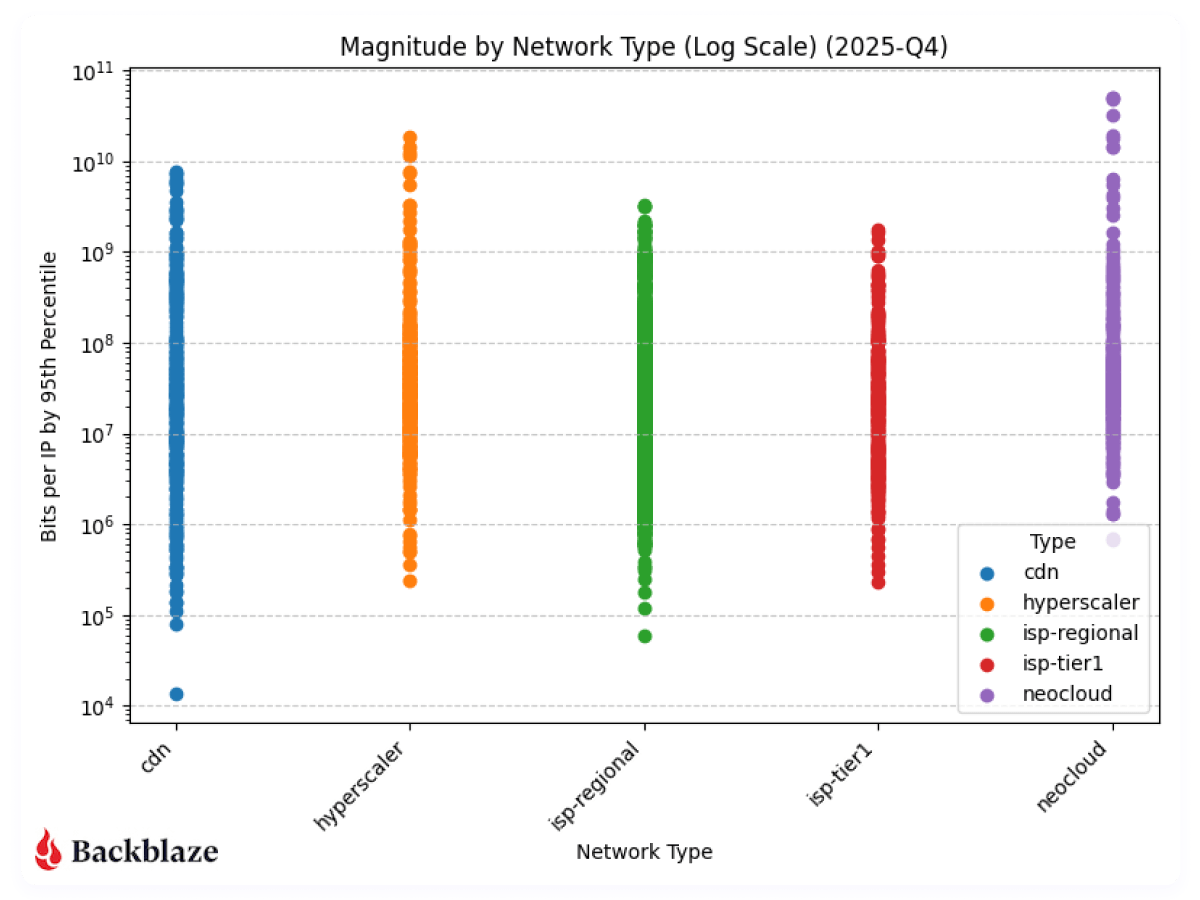
Heatmap #2: Where were the data transfers with the most magnitude (bits per IP address)?

Another metric we record is bits per IP or what we termed in our last report “magnitude.” This combination of the amount of traffic transferred with how many actors are involved per network is a good proxy to measure how heavy or impactful individual data flows are. In short:

  • High volume, many IPs: Easier to distribute and load-balance across infrastructure. And many source and destination pairs means that we can traffic engineer at the WAN layer, sending some traffic over one provider and some over another.
  • High volume, few IPs: More difficult, but more interesting, from a NetEng perspective. 

With B2 Overdrive, we routinely support client transfers starting at 100Gbps up to 1Tbps of throughput.These high-magnitude flows show up clearly in the data, especially in regions serving AI-heavy neocloud endpoints. Seeing these patterns emerge in the data validates that customers are actively using the platform the way it was designed.

Heatmap #3: How many unique addresses do we interact with?

Uniqueness—measured by the number of distinct IP addresses per network type—adds another dimension to the story. 

  • US-West shows the highest overall uniqueness, driven by its larger number of data centers and mix of workloads.
  • Neocloud traffic, by contrast, tends to involve fewer, more persistent endpoints, consistent with AI pipelines that rely on stable, long-standing connections between storage and compute. 

This contrast reveals a broader trend: AI networking is less about many-to-many communication and more about sustained high-throughput relationships between specialized systems.

A chart showing the number of unique IP addresses that sent or received data to the Backblaze networks by region.
Communication uniqueness across our regions to each network type

Summary: Early indicators of an AI-native network era

This quarter represents an early but important snapshot of how AI is reshaping network behavior:

  • AI-driven traffic is concentrated and heavy (not groundbreaking news by any means, but interesting to see it played out on a network).
  • Neocloud connectivity is a defining feature of data movement today.
  • Data gravity is pulling storage, compute, and network design into tighter alignment.

This is our first look at these patterns specifically. As we gather more quarters of data, we’ll be watching closely to see how cyclical neocloud activity becomes, how regional concentrations shift, and how the growing ecosystem of AI-focused ISVs continues to change the shape of the network.

Quarter over quarter data

Last quarter we started capturing data and metrics that we were interested in tracking over time. This represents our first full quarter of data as we only started tracking in August of 2025, so it’s still early to start to see trends, but we’re including the visualizations for fidelity. 

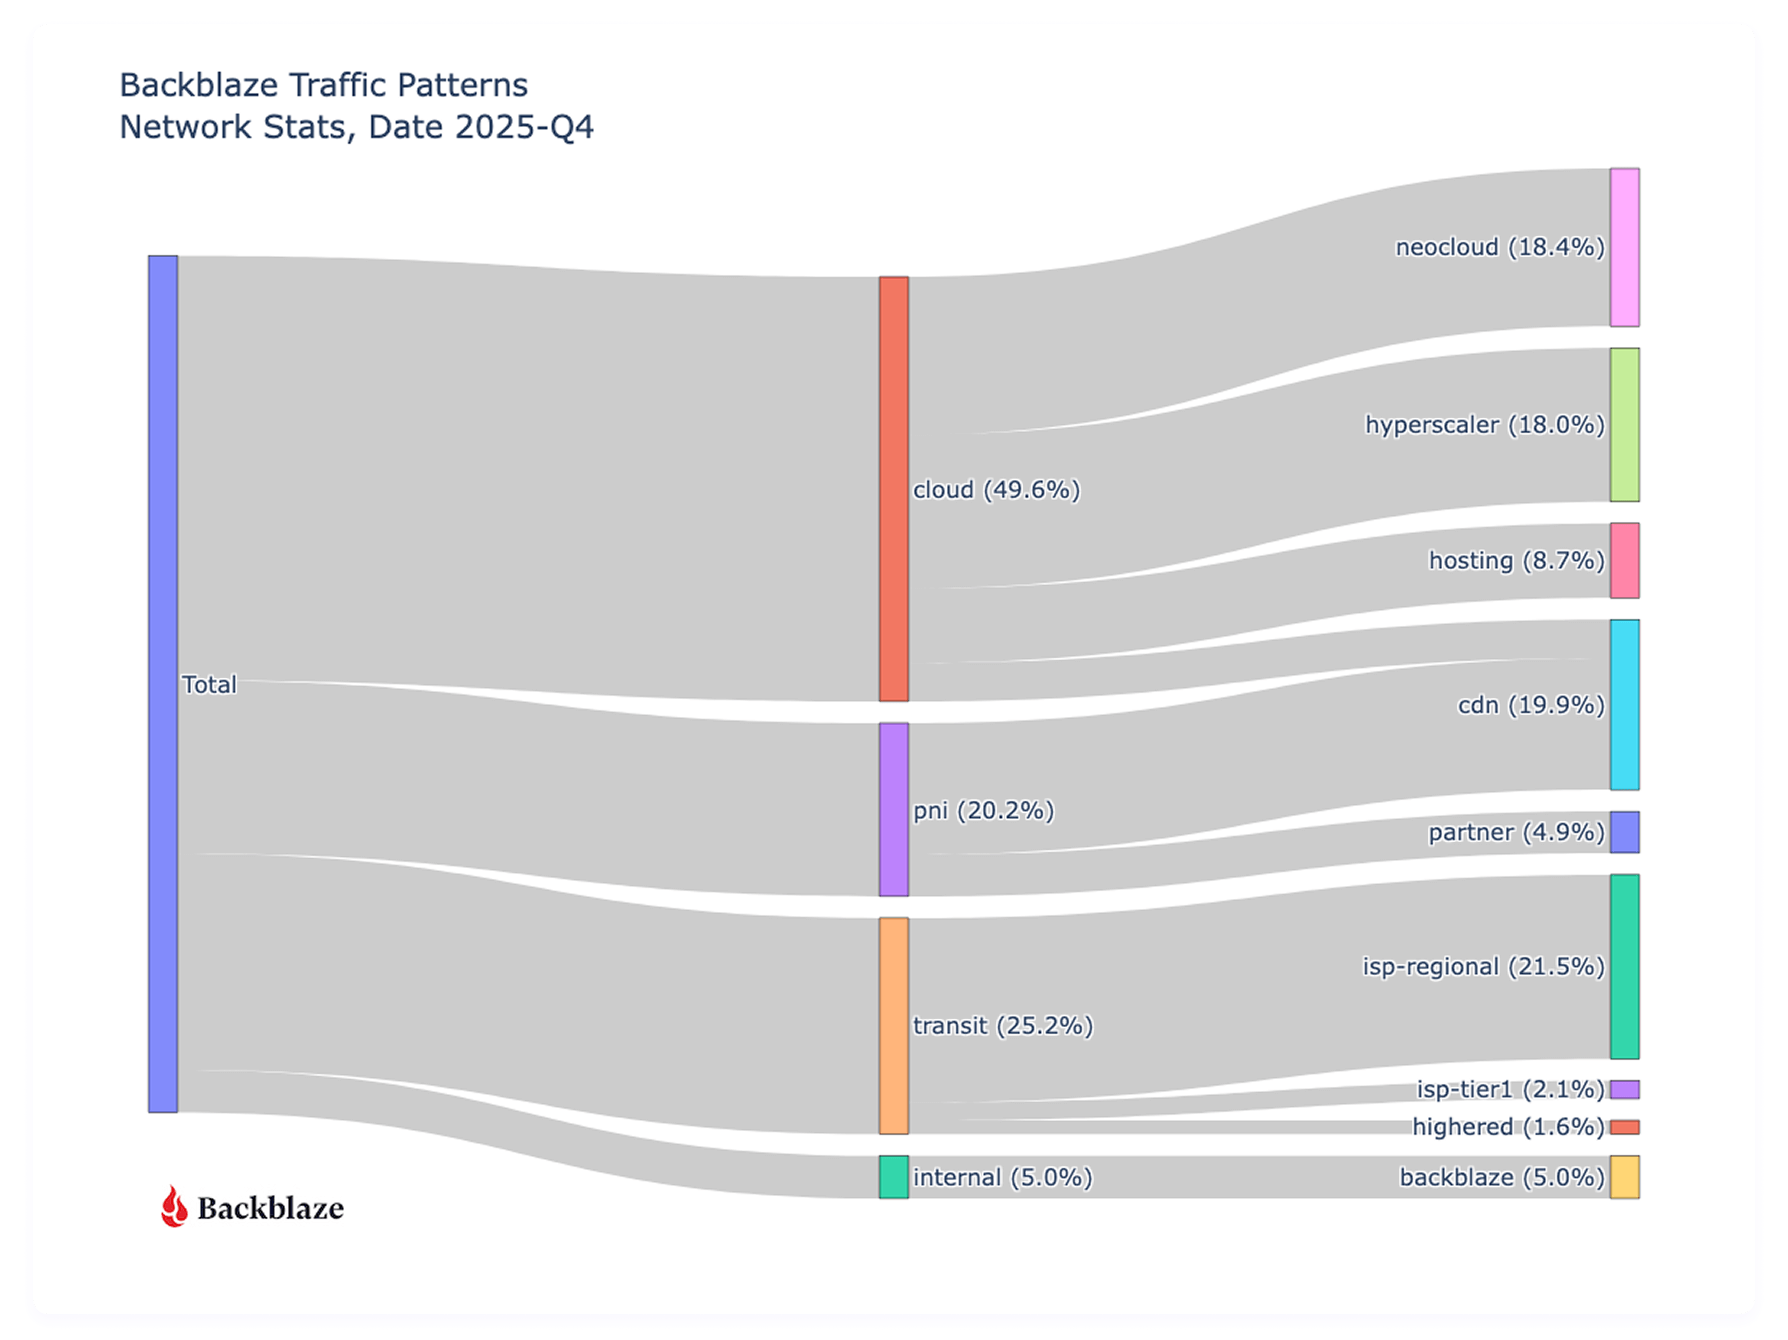
First let’s take a look at where all our traffic goes from a global perspective with an updated view of last quarter.

A Sankey diagram that tracks total data traffic flow between Backblaze and different types providers for Q4 2025.
Sankey diagram of all August ingress and egress traffic grouped by type of network

Traffic to other clouds has increased (36.2% to 49.6%) since we last reported in August of 2025, with a slight decrease (19.8% to 18.4%) in Neocloud destinations, but a large increase (3.5% to 18%) to hyperscalers. It’s too early to call these things statistically significant trends or patterns that impact the cloud storage industry broadly, because they’re reflective of what types of customers Backblaze specifically has and our sampling range is only a quarter. That said, we do see an overall increase in cloud to cloud traffic, but the higher percentage to the type of clouds rotated from last quarter.

Next, let’s look at the magnitude of our network traffic based on the category of the traffic destination. As a reminder, magnitude represents the amount of traffic transferred with how many actors are involved per network. 

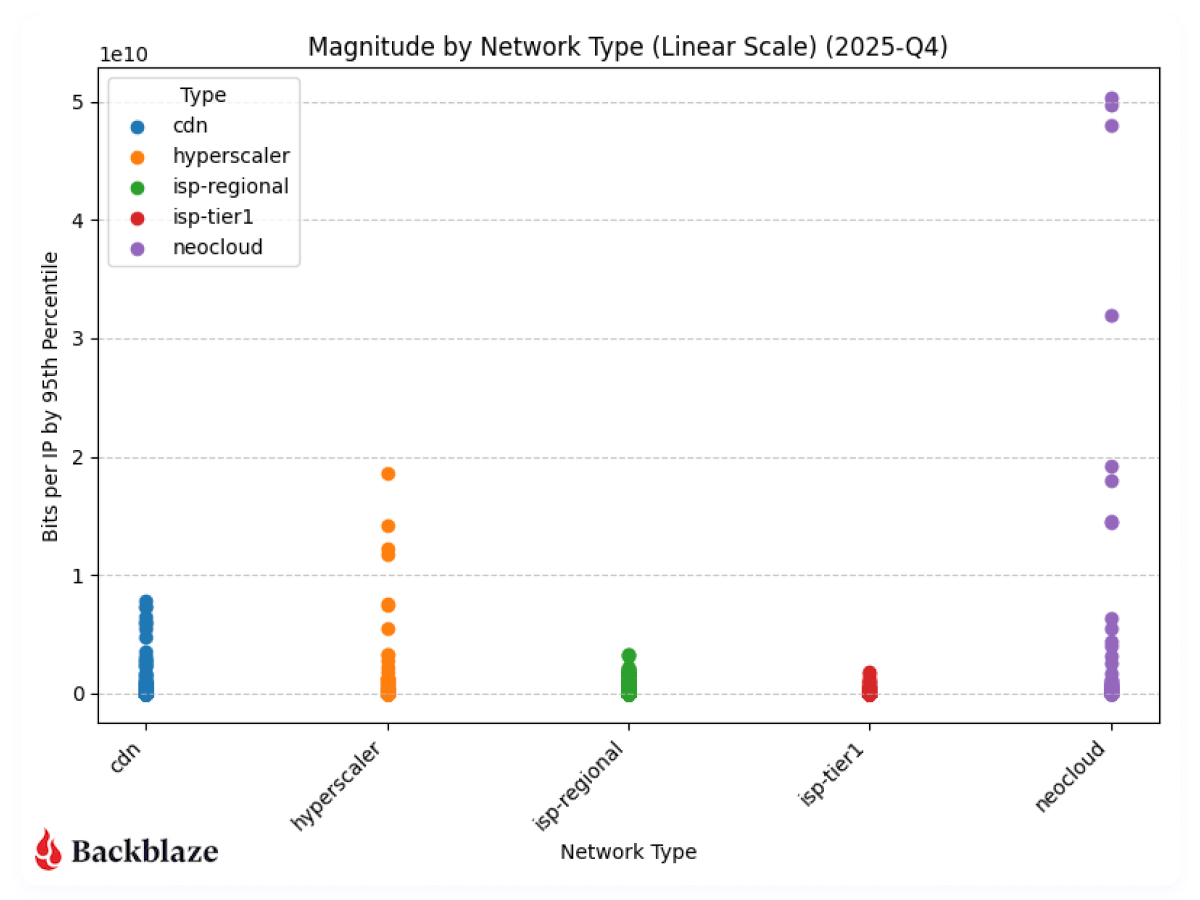
Next, to be consistent with our previous report, we’ll look at magnitude on a linear scale. 

With more datapoints, we can clearly see the magnitude of the neocloud and hyperscaler transfers when compared to other network types. As above, it’s a bit early to claim concrete quarter over quarter patterns, but we’ll keep monitoring and updating the dataset. 

What’s next?

Next quarter will be the first where we have true quarter over quarter data to analyze, and we’ll be back with more on how AI-driven flows change quarter over quarter. And as we get more data, we’re interested in looking at other trends like IPv4 vs. IPv6 traffic, cross-cloud connectivity trends, and revisiting the concentration analysis we did this quarter. 

Anything specific you want to see? Let us know in the comments or reach out to our Evangelism team. Or, keep up-to-date with the latest technical content with our Developer Newsletter. 

The post Network Stats for Q4 2025: Neocloud Traffic Trends appeared first on Backblaze Blog | Cloud Storage & Cloud Backup
Building a Conversational AI Chatbot Website with Backblaze B2 + LangChain

Post Syndicated from Pat Patterson original https://www.backblaze.com/blog/building-a-conversational-ai-chatbot-website-with-backblaze-b2-langchain/

A decorative image showing a cloud with the Backblaze logo with code imagery.

In an earlier blog post, I explained how to build your own LLM with Backblaze B2 + Jupyter Notebook, implementing a simple conversational AI chatbot using the LangChain AI framework to implement retrieval-augmented generation (RAG). The notebook walks you through the process of loading PDF files from a Backblaze B2 Bucket into a vector store, running a local instance of a large language model (LLM) and combining those to form a chatbot that can answer questions on its specialist subject.

That article generated a lot of interest, and a few questions:

  • “Could you make this into a web app, like ChatGPT?”
  • “Could you use this with OpenAI? DeepSeek?”
  • “Could I load multiple collections of documents into this?”
  • “Could I run multiple LLMs and compare them?”
  • “Can I add new documents to the vector store as they are uploaded to the bucket?”

The answer to all of these questions is “Yes!”

Today, I’ll present a simple conversational AI chatbot web app with a ChatGPT-style UI that you can easily configure to work with OpenAI, DeepSeek, or any of a range of other LLMs. In future blog posts, I’ll extend this to allow you to configure multiple LLMs and document collections, and integrate with Backblaze B2’s Event Notifications feature to load documents into the vector store within seconds of them being uploaded.

And, here’s a very short video of the chatbot in action:

Editorial note: A version of this article was previously published on the New Stack.

RAG basics

Retrieval-augmented generation, or RAG for short, is a technique that applies the generative features of an LLM to a collection of documents, resulting in a chatbot that can effectively answer questions based on the content of those documents.

A typical RAG implementation splits each document in the collection into a number of roughly equal-sized, overlapping chunks, and generates an embedding for each chunk. Embeddings are vectors (lists) of floating point numbers with hundreds or thousands of dimensions. The distance between two vectors indicates their similarity. Small distances indicate high similarity and large distances indicate low similarity.

The RAG app then loads each chunk, along with its embedding, into a vector store. The vector store is a special-purpose database that can perform a similarity search–given a piece of text, the vector store can retrieve chunks ranked by their similarity to the query text by comparing the embeddings.

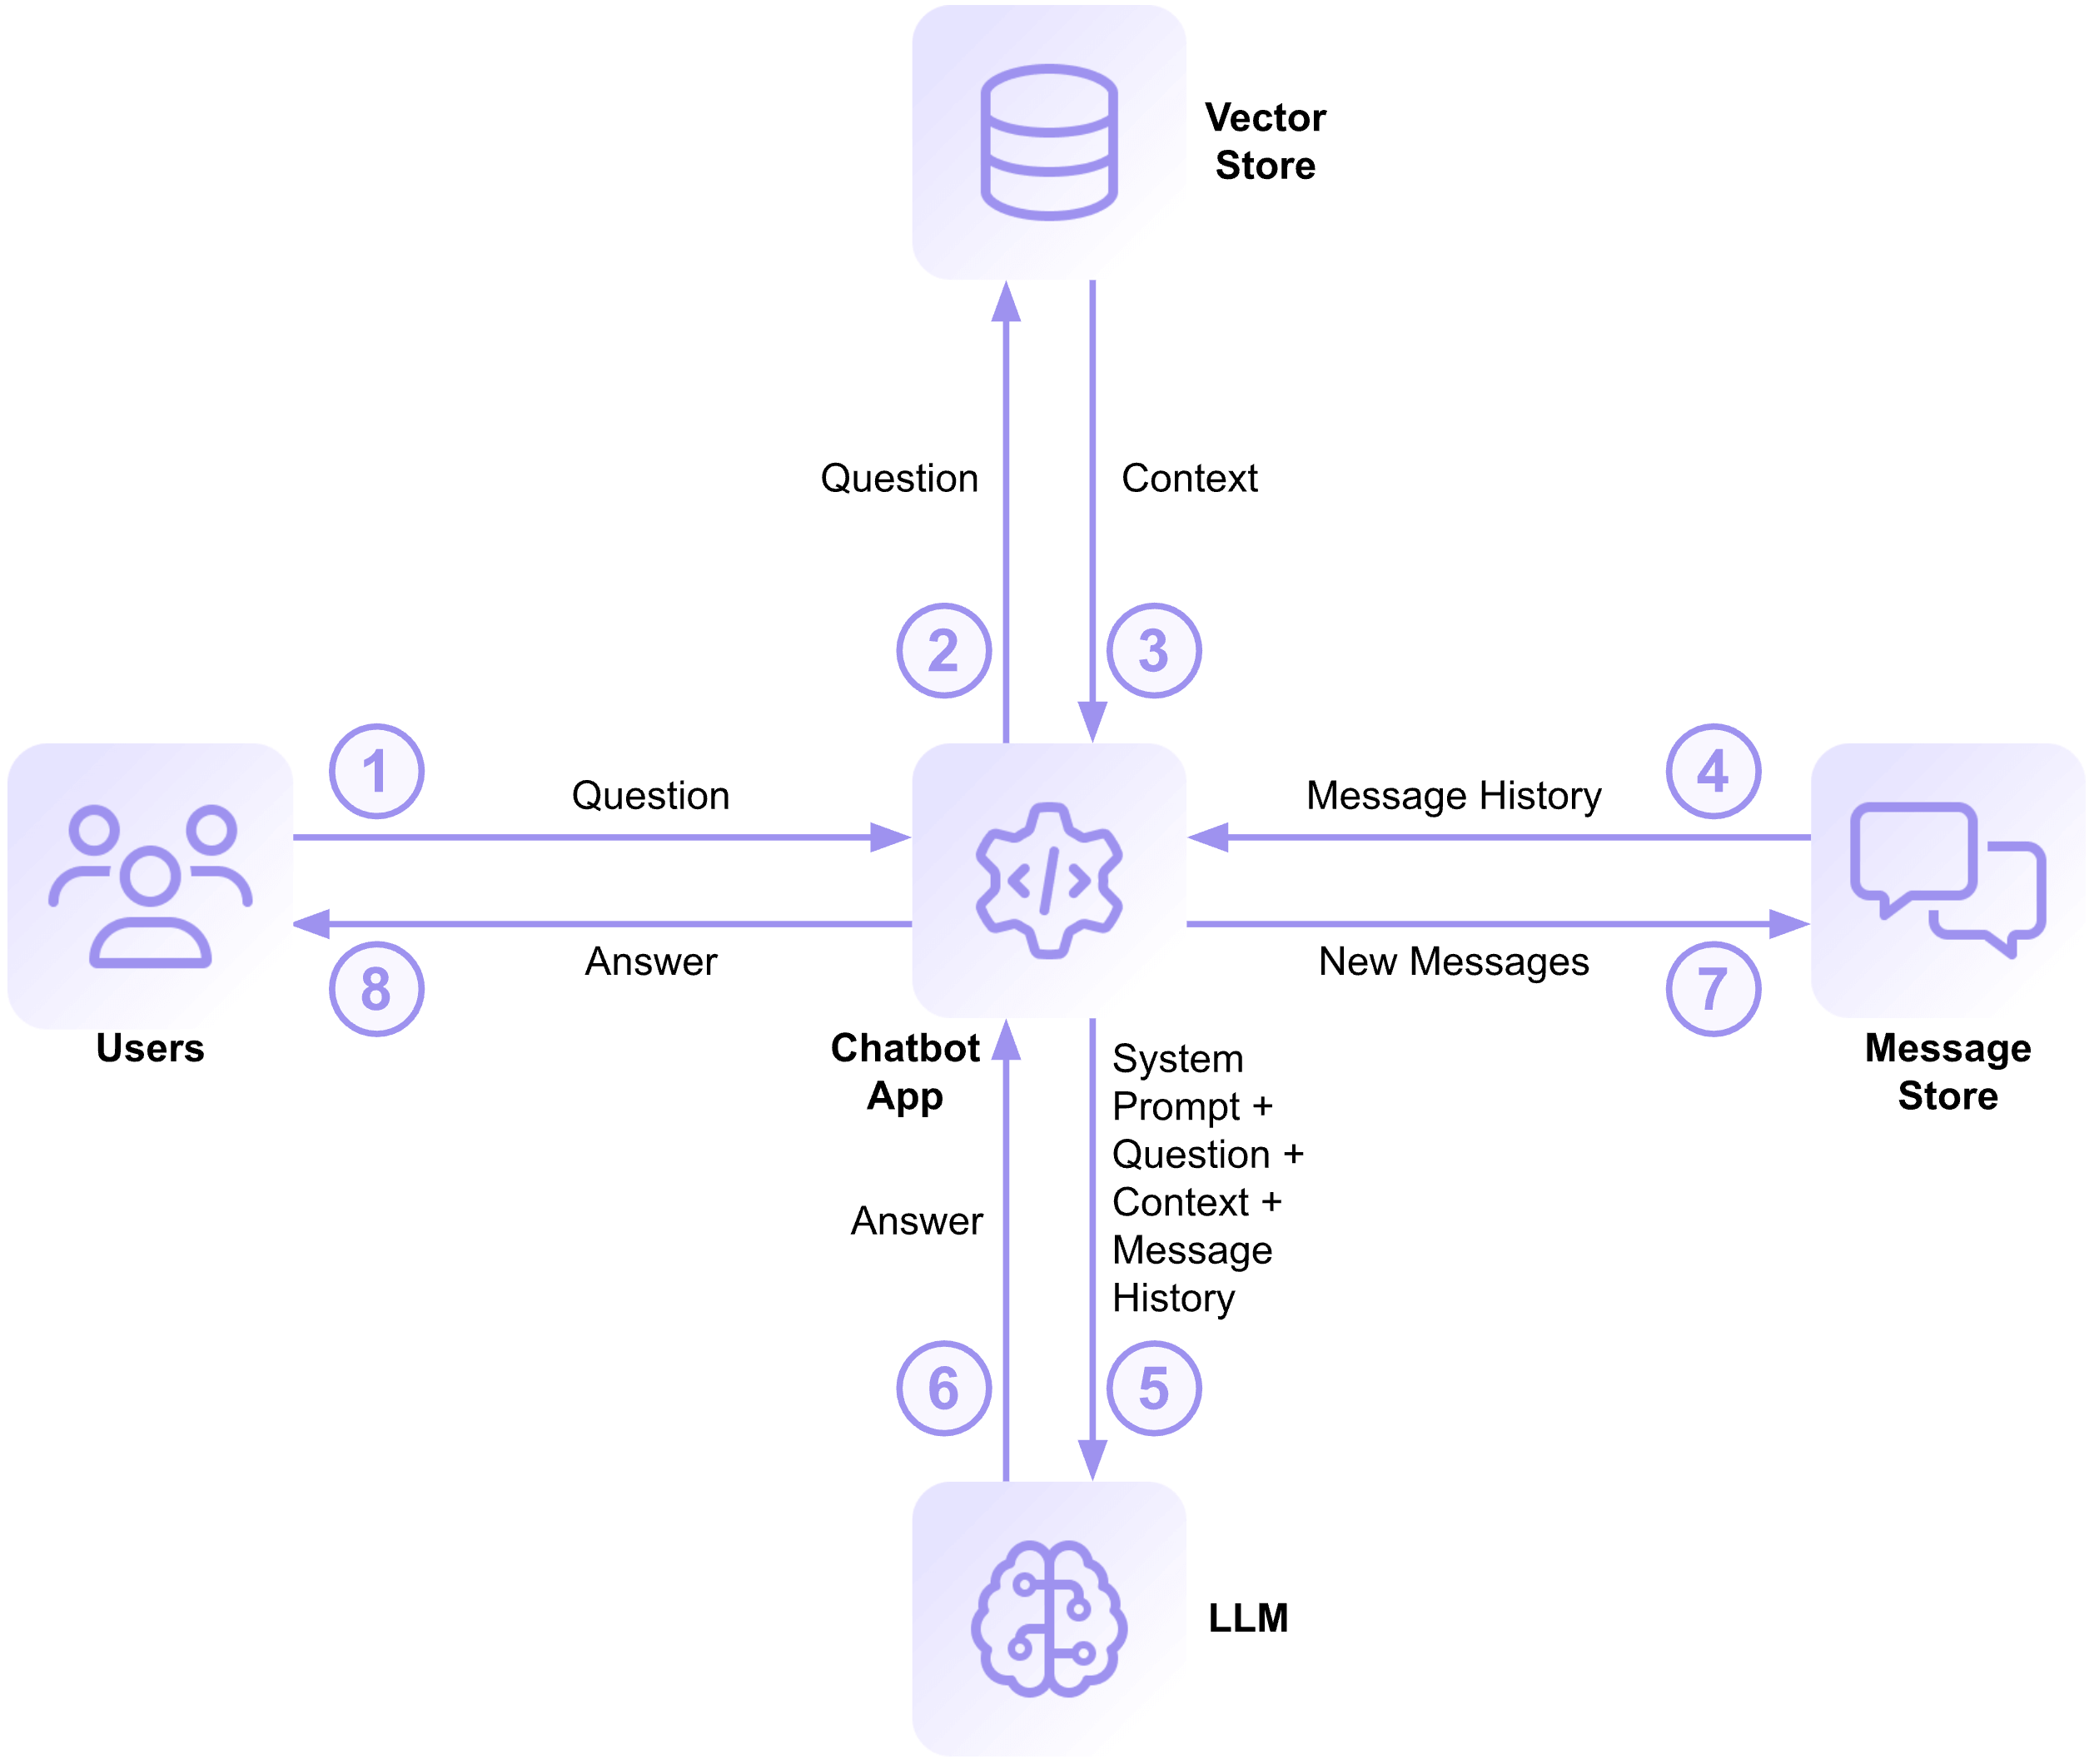
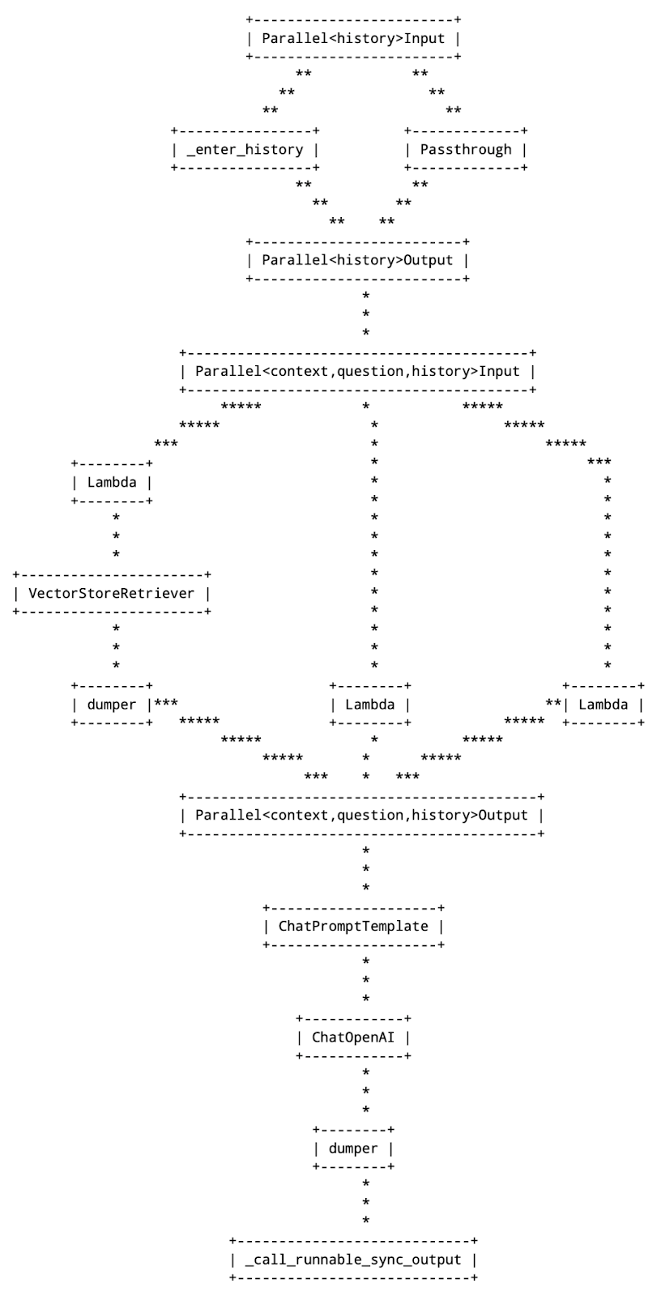
Let’s put the pieces together:

Given a question from the user (1), the RAG app can query the vector store for chunks of text that are similar to the question (2). This will be the context that helps the LLM answer the user’s question. Here’s a concrete example using the Backblaze documentation collection: Given the question, “Tell me about object lock,” the vector store returns four document chunks, each of about 170 words, to the app (3). Here is a link to the text of, and a short extract from, each chunk:

  • Object Lock: With Object Lock Legal Hold, files are prevented from being changed or deleted, but the immutability does not have a defined retention period.
  • Object Lock: You can enable Object Lock on a bucket when you create a new bucket or on an existing bucket.
  • Object Lock: Object Lock in Backblaze B2 was designed with the Immutability feature in Veeam Backup & Replication in mind.
  • Enable Object Lock with the S3 Compatible API: To enable Object Lock on an existing S3 compatible bucket, add the x-amz-bucket-object-lock-token header with a value of 1 to the S3 Put Object Lock Configuration API call.

Unsurprisingly, three of the four results are extracts from the main documentation article on Object Lock.

In order to provide a conversational experience, the RAG app maintains a chat history in a message store. The RAG app retrieves the message history (4) to form part of the query it will send to the LLM.

A system prompt sets the guidelines for the LLM to generate responses. In a RAG, the system prompt typically specifies that the response should be based on retrieved document data rather than model memorization, and attempts to prevent hallucinations by ensuring that the model does not fabricate information if no relevant documents are found. Here is the system prompt from the RAG app:

Use the following pieces of context and the message history to answer the question at the end. If you don't know the answer,  just say that you don't know, don't try to make up an answer.

The RAG submits the system prompt, the context, the last few messages in the conversation, and the user’s question to the LLM (5), which generates a, hopefully useful, response (6). Here’s the answer it provided to the above question:

Object Lock is a feature that allows users to enforce immutability on files stored in cloud storage, specifically in services like Backblaze B2 and AWS S3. Here are the key points about Object Lock:

  1. Immutability: Once a file is locked, it cannot be modified or deleted until a specified retention period expires or a legal hold is lifted.
  2. Retention Periods: Users can set a retention period when locking a file. During this time, the file remains immutable, meaning it cannot be changed or deleted.
  3. Legal Hold: Users can place files under a legal hold, which prevents modifications or deletions indefinitely until the hold is removed.
  4. Enabling Object Lock: Object Lock can be enabled for new buckets or existing ones, but it must be turned on at the bucket level before files are uploaded.
  5. Integrations: Some applications, like Veeam Backup & Replication, offer built-in support for Object Lock, making the process easier for users when they want to ensure file immutability during backups.
  6. No Extra Cost: There is no additional fee for using Object Lock; however, standard storage charges for the locked files still apply.
  7. Mistakes in Locking: If a user locks a file for longer than intended, they may need to contact support to resolve the situation, which could involve closing their storage account in some cases.

Overall, Object Lock is a crucial feature for organizations that need to ensure data integrity and compliance with regulations concerning data retention.

The RAG app adds the user’s question and the LLM’s response to the message store (7), returns the answer to the user (8), and awaits the next question.

A quick tour of the sample app

The sample app is on GitHub at https://github.com/backblaze-b2-samples/ai-rag-app. The app is open source, under the MIT license, so you can use it as a basis for your own experimentation without any restrictions. The app was originally written to demonstrate RAG with Backblaze B2 Cloud Storage, but it works with any S3 compatible object store.  

The README file covers configuration and deployment in some detail; in this blog post, I’ll just give you a high-level overview. The sample app is written in Python using the Django web framework. API credentials and related settings are configured via environment variables, while the LLM and vector store are configured via Django’s settings.py file:

CHAT_MODEL: ModelSpec = {
'name': 'OpenAI',
'llm': {
'cls': ChatOpenAI,
'init_args': {
'model': "gpt-4o-mini",
}
},
}

# Change source_data_location and vector_store_location to match your environment
# search_k is the number of results to return when searching the vector store
DOCUMENT_COLLECTION: CollectionSpec = {
'name': 'Docs',
'source_data_location': 's3://blze-ev-ai-rag-app/pdfs',
'vector_store_location': 's3://blze-ev-ai-rag-app/vectordb/docs/openai',
'search_k': 4,
'embeddings': {
'cls': OpenAIEmbeddings,
'init_args': {
'model': "text-embedding-3-large",
},
},
}

The sample app is configured to use OpenAI GPT-4o mini, but the README explains how to use different online LLMs such as DeepSeek V3 or Google Gemini 2.0 Flash, or even a local LLM such as Meta Llama 3.1 via the Ollama framework. If you do run a local LLM, be sure to pick a model that fits your hardware. I tried running Meta’s Llama 3.3, which has 70 billion parameters (70B), on my MacBook Pro with the M1 Pro CPU. It took nearly three hours to answer a single question! Llama 3.1 8B was a much better fit, answering questions in less than 30 seconds.

Notice that the document collection is configured with the location of a vector store containing the Backblaze documentation as a sample dataset. The README file contains an application key with read-only access to the PDFs and vector store so you can try the application without having to load your own set of documents.

If you want to use your own document collection, a pair of custom commands allow you to load them from a Backblaze B2 Bucket into the vector store and then query the vector store to test that it all worked.

First, you need to load your data:

% python manage.py load_vector_store
Deleting existing LanceDB vector store at s3://blze-ev-ai-rag-app/vectordb/docs
Creating LanceDB vector store at s3://blze-ev-ai-rag-app/vectordb/docs
Loading data from s3://blze-ev-ai-rag-app/pdfs in pages of 1000 results
Successfully retrieved page 1 containing 618 result(s) from s3://blze-ev-ai-rag-app/pdfs
Skipping pdfs/.bzEmpty
Skipping pdfs/cloud_storage/.bzEmpty
Loading pdfs/cloud_storage/cloud-storage-about-backblaze-b2-cloud-storage.pdf
Loading pdfs/cloud_storage/cloud-storage-add-file-information-with-the-native-api.pdf
Loading pdfs/cloud_storage/cloud-storage-additional-resources.pdf
...
Loading pdfs/v1_api/s3-put-object.pdf
Loading pdfs/v1_api/s3-upload-part-copy.pdf
Loading pdfs/v1_api/s3-upload-part.pdf
Loaded batch of 614 document(s) from page
Split batch into 2758 chunks
[2025-02-28T01:26:11Z WARN lance_table::io::commit] Using unsafe commit handler. Concurrent writes may result in data loss. Consider providing a commit handler that prevents conflicting writes.
Added chunks to vector store
Added 614 document(s) containing 2758 chunks to vector store; skipped 4 result(s).
Created LanceDB vector store at s3://blze-ev-ai-rag-app/vectordb/docs. "vectorstore" table contains 2758 rows

Now you can verify that the data is stored by querying the vector store. Notice how the raw results from the vector store include an S3 URI identifying the source document:

% python manage.py search_vector_store 'Which B2 native APIs would I use to upload large files?' 
2025-03-01 02:38:07,740 ai_rag_app.management.commands.search INFO Opening vector store at s3://blze-ev-ai-rag-app/vectordb/docs/openai
2025-03-01 02:38:07,740 ai_rag_app.utils.vectorstore DEBUG Populating AWS environment variables from the b2 profile
Found 4 docs in 2.30 seconds
2025-03-01 02:38:11,074 ai_rag_app.management.commands.search INFO
page_content='Parts of a large file can be uploaded and copied in parallel, which can significantly reduce the time it takes to upload terabytes of data. Each part can be anywhere from 5 MB to 5 GB, and you can pick the size that is most convenient for your application. For best upload performance, Backblaze recommends that you use the recommendedPartSize parameter that is returned by the b2_authorize_account operation. To upload larger files and data sets, you can use the command-line interface (CLI), the Native API, or an integration, such as Cyberduck. Usage for Large Files Generally, large files are treated the same as small files. The costs for the API calls are the same. You are charged for storage for the parts that you uploaded or copied. Usage is counted from the time the part is stored. When you call the b2_finish_large_file' metadata={'source': 's3://blze-ev-ai-rag-app/pdfs/cloud_storage/cloud-storage-large-files.pdf'}
...

The core of the sample application is the RAG class. There are several methods that create the basic components of the RAG, but here we’ll look at how the _create_chain() method brings together the system prompt, vector store, message history, and LLM.

First, we define the system prompt, which includes a placeholder for the context—those chunks of text that the RAG will retrieve from the vector store:

# These are the basic instructions for the LLM
system_prompt = (
"Use the following pieces of context and the message history to "
"answer the question at the end. If you don't know the answer, "
"just say that you don't know, don't try to make up an answer. "
"\n\n"
"Context: {context}"
)

Then we create a prompt template that brings together the system prompt, message history, and the user’s question:

# The prompt template brings together the system prompt, context, message history and the user's question
prompt_template = ChatPromptTemplate(
[
("system", system_prompt),
MessagesPlaceholder(variable_name="history", optional=True, n_messages=10),
("human", "{question}"),
]
)

Now we use LangChain Expression Language (LCEL) to bring the various components together to form a chain. LCEL allows us to define a chain of components declaratively; that is, we provide a high-level representation of the chain we want, rather than specifying how the components should fit together. 

Notice the log_data() helper method—it simply logs its input and passes it on to the next component in the chain.

# Create the basic chain
# When loglevel is set to DEBUG, log_input will log the results from the vector store
chain = (
{
"context": (
itemgetter("question")
| retriever
| log_data('Documents from vector store', pretty=True)
),
"question": itemgetter("question"),
"history": itemgetter("history"),
}
| prompt_template
| model
| log_data('Output from model', pretty=True)
)

Assigning a name to the chain allows us to add instrumentation when we invoke it:

# Give the chain a name so the handler can see it
named_chain: Runnable[Input, Output] = chain.with_config(run_name="my_chain")

Now, we use LangChain’s RunnableWithMessageHistory class to manage adding and retrieving messages from the message store:

# Add message history management
return RunnableWithMessageHistory(
named_chain,
lambda session_id: RAG._get_session_history(store, session_id),
input_messages_key="question",
history_messages_key="history",
)

Finally, the log_chain() function prints an ASCII representation of the chain to the debug log:

log_chain(history_chain, logging.DEBUG, {"configurable": {'session_id': 'dummy'}})

This is the output:

The RAG class’ invoke() function, in contrast, is very simple. Here is the key section of code:

response = self._chain.invoke(
{"question": question},
config={
"configurable": {
"session_id": session_key
},
"callbacks": [
ChainElapsedTime("my_chain")
]
},
)

The input to the chain is a Python dictionary containing the question, while the config argument configures the chain with the Django session key and a callback that annotates the chain output with its execution time. Since the chain output contains Markdown formatting, the API endpoint that handles requests from the front end uses the open source markdown-it library to render the output to HTML for display.

The remainder of the code is mostly concerned with rendering the web UI. One interesting facet is that the Django view, responsible for rendering the UI as the page loads, uses the RAG’s message store to render the conversation, so if you reload the page, you don’t lose your context.

Take this code and run it!

The sample AI RAG application is open source under the MIT license, and I encourage you to use it as the basis for your own RAG exploration. The README file suggests a few ways you could extend it, and I also draw your attention to conclusion of the README if you are thinking of running the app in production:

[…] in order to get you started quickly, we streamlined the application in several ways. There are a few areas to attend to if you wish to run this app in a production setting:

Above all, have fun! AI is a rapidly evolving technology, with vendors and open source projects releasing new capabilities every day. I hope you find this app a useful way of jumping in.

The post Building a Conversational AI Chatbot Website with Backblaze B2 + LangChain appeared first on Backblaze Blog | Cloud Storage & Cloud Backup
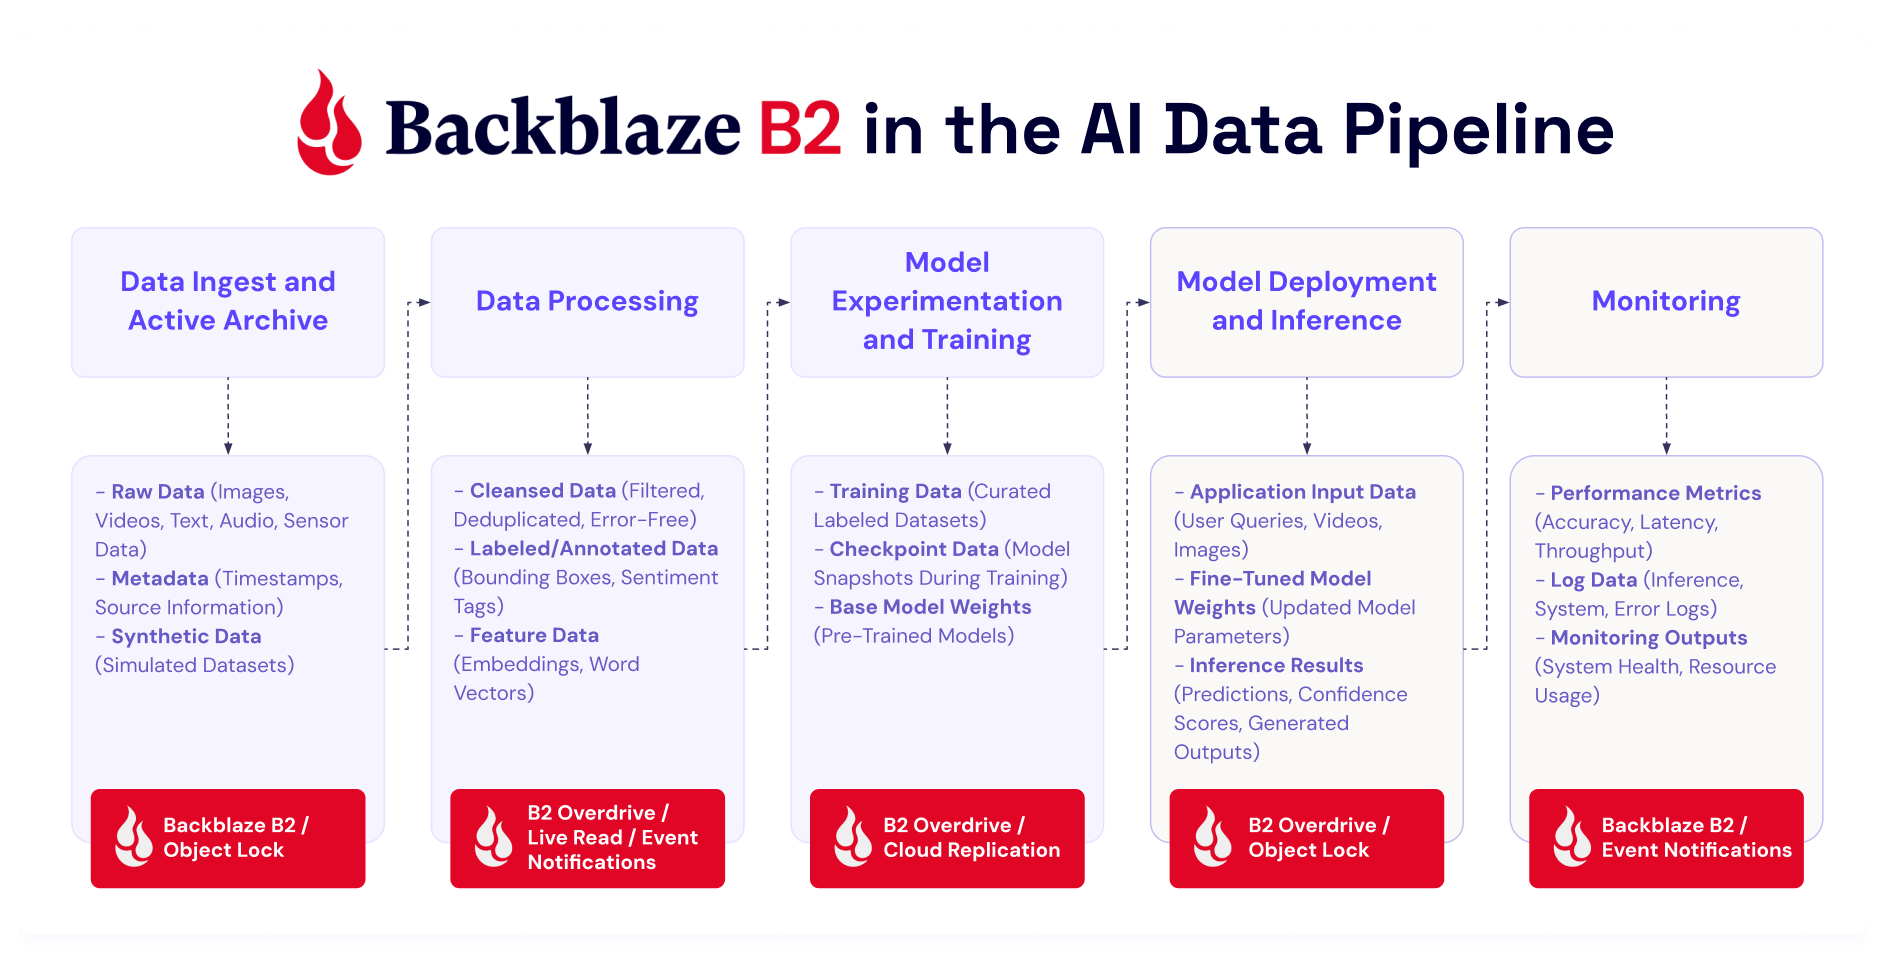
One Simple Change That Made Our Exabyte-Scale Storage Faster

Post Syndicated from Jerry Sha original https://www.backblaze.com/blog/one-simple-change-that-made-our-exabyte-scale-storage-faster/

A decorative image showing various towers and a cloud.

When you’re moving exabytes of data, every network request, every CPU cycle, every byte matters. Recently, I had the chance to revisit a part of our system that’s been quietly humming along for years. With one small rethink, we helped give our download performance a serious boost.

The idea was almost laughably simple: combine two separate requests into one. But when you’re operating at massive scale, even a “simple” change can make a huge difference.

Curious how we think about performance at scale?

From our new series on engineering innovations, check out Analyzing Performance at Exabyte Scale and What Powers the Performance of Backblaze for a deeper dive into the engineering principles that drive our storage platform.

The challenge: Why we had 40 requests per download

Before the change, downloading a file meant:

  • A “download coordinator” pod would reach out across the 20 pods that make up a Vault to grab metadata.
  • Once it had those, it would figure out where the needed bytes lived.
  • Then it would go back and request the actual data.

That meant 40 separate requests just to get the ball rolling on every download.

The fix: Smarter reads with half the overhead

At some point, it clicked for me: why were we doing this in two steps? The original setup only pulled the bare minimum of data. But what if we just grabbed everything we needed at once? There wasn’t a good reason not to. So I refactored the process so that a pod could grab both the shard header and the data in a single request.

Now:

  • The coordinator still orchestrates the work.
  • The receiving pod reads the header, figures out what it needs, and pulls the data—all internally. By shifting this responsibility to the receiving pod, we eliminate a network round trip per pod—20 round trips in total. 
  • The combined result is sent back to the coordinator in a single step.

After the fix, we’re still reading the same amount of data from disk, so disk I/O remains unchanged, but network performance improved significantly. Instead of kicking off 40 network operations, we’re down to about half that. Less traffic, less overhead, faster performance.

It was a simple fix, but the project required a significant amount of software engineering work as well. By shifting responsibilities to the “receiving pod” the coordinator needed to learn to perform lots of just-in-time reasoning about the nature of the download, which required rethinking how we architected portions of the download code.

Why it didn’t just instantly double download performance

If you’re thinking, “shouldn’t that make downloads twice as fast?”—not quite.

Here’s why: Big files get broken into “stripes” during download, and my change only optimizes the first stripe request. Smaller files (a big chunk of our traffic) see the full benefit because they often fit into a single stripe. For larger files, though, the improvement only affects a small part of the overall download, so the impact is more limited.

How we measured the impact

Measuring the real-world effect turned out to be trickier than I expected. Our download traffic isn’t steady; it’s spiky. Under normal conditions, our system wasn’t hitting capacity limits which made it hard to clearly see changes in download performance. 

But in our dedicated performance testing environment, where we could send a controlled load of downloads, the improvement was crystal clear. With this change, our system could handle a much higher peak load—great news for handling things like backup surges, AI training runs, and large enterprise downloads. 

Beyond download performance: System-wide benefits

One of the coolest side effects? This doesn’t just help customer downloads. It also speeds up internal operations like vault recomputing data drives and server-side copies.

By freeing up CPU cycles that used to be wasted on multiple requests, we open the door for better performance everywhere. And hey, maybe even some minor energy savings—less CPU load means less heat, less power.

What this taught me about optimization

When you’re trying to optimize a massive system, it’s tempting to chase performance with complicated solutions: more threads, smarter caches, fancier hardware.

But sometimes, the real win is just about thinking differently. Questioning assumptions. Asking, “Wait, why are we doing it this way?”

For me, this project was a great reminder that even at exabyte scale, the simplest solution can be the most impactful.

The post One Simple Change That Made Our Exabyte-Scale Storage Faster appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Iceberg on Backblaze B2

Post Syndicated from Pat Patterson original https://www.backblaze.com/blog/iceberg-on-backblaze-b2/

A decorative image showing icons of different file types on a grid superimposed over a cloud.

If you work with cloud storage and data lakes, you’re likely hearing the word “Iceberg” with increasing frequency, occasionally prefixed by “Apache”. What is Apache Iceberg, and how can you leverage it to efficiently store data in object stores such as Backblaze B2 Cloud Storage? I’ll answer both of those questions in this blog post.

But, first, join me on a brief trip back in time to the beginning of the twenty-first century, a long-ago time before the emergence of big data and cloud computing.

A timely shoutout to the Data Council conference

We recently attended the 2025 Data Council conference and caught Ryan Blue, co-creator of Apache Iceberg’s excellent presentation (featuring some very entertaining slides).

If you want to hear more about topics like this one, feel free to join us at Backblaze Weekly, an ongoing webinar series where we discuss all things Backblaze.

An image of Ryan Blue speaking at the 2025 Data Council conference.
Ryan Blue speaking at the 2025 Data Council conference. Note: His shirt says “the future is open”. We agree!

CSV: The lingua franca of tabular data

In the early 2000s, if you were working with tabular data, you were likely using either a relational database management system (RDBMS), such as Oracle Database, or a spreadsheet, likely Microsoft Excel.

Data stored in an RDBMS is highly structured, meaning that it MUST conform to a predefined schema. For example, you might create an employee table with columns such as first name, last name, date of birth, hire date, and so on. The database schema holds metadata such as the name and data type of each column, whether that column must have a value, relationships between tables, and so on.

A spreadsheet, on the other hand, has some structure—data is arranged in rows and columns, similarly to an RDBMS–but each cell can contain anything: text, a number, a formula referencing other cells, even an image in today’s spreadsheets. We say that a spreadsheet is semi-structured data.

At the turn of the century, each database and spreadsheet had its own proprietary file format, optimized for its own requirements, and often not at all publicly documented, but the need to be able to exchange data between applications led to broad adoption of a file format to allow just that: comma-separated values, or CSV.

Here’s a simple example of some tabular data represented as CSV:

employee_id,first_name,last_name,reports_to,job_title,is_manager
1,Gleb,Budman,,CEO,1
123,Patrick,Thomas,1,"VP of Marketing",1
45,Yev,Pusin,123,"Head of Communications and Community",1
678,Pat,Patterson,45,"Chief Technical Evangelist",0

CSV is simple and flexible enough that it was easy for me to type that example up manually and import it into Microsoft Excel with no problems at all. Note that, as well as the commas, the double quotes in the CSV data are part of the file format, and do not appear in the imported data:

A screenshot of an Excel spreadsheet.

CSV has a lot of advantages: It’s simple; flexible; widely understood; the optional header line means that data can be somewhat self-describing; and it’s not controlled by any single vendor.

CSV does, however, also have a few disadvantages, including:

  • There’s no schema; nothing in that file expresses that the values in the first column, apart from the header, must be integers.
  • It’s difficult to represent complex or hierarchical datasets.
  • Data is stored as text, which is inefficient for numerical and repetitive data. Text representations of numbers occupy more storage than binary, and applications must convert them to binary when loading the file and convert them back to text when saving it.

Avro, Parquet and ORC: File formats for big data

The emergence of open-source distributed computing frameworks such as Apache Hadoop and, later, Apache Spark, in the first two decades of this century drove the creation and adoption of more efficient ways of storing tabular data. Avro, Parquet and ORC, all Apache projects, are binary file formats that address shortcomings of CSV, such as encapsulating schema alongside the data.

Avro, like CSV, is designed for row-oriented data, which makes it well-suited to use cases that involve appending new data to files. Parquet and ORC, in contrast, are column-oriented file formats, perfect for online analytical processing (OLAP) use cases where, for example, an application might read an entire column from a table to calculate the sum of its values. As well as storing numbers in a binary representation, Parquet and ORC can also reduce file size through compression strategies such as run-length encoding.

Here’s a concrete example: The Drive Stats data set for December 2024 occupies 3.7GB of storage in CSV format. As Parquet, the same data consumes just 242MB, a data compression ratio of more than 15:1.

Why does it matter if your dataset is smaller? Well, beyond just cost savings, which are amplified when dealing with huge datasets, smaller files mean that running queries against full datasets takes less time, which reduces server load, compute costs, and so on.  

From file formats to table formats and data lakes

Apache Hadoop’s original use case was as an implementation of MapReduce, a programming model for manipulating large datasets. Engineers at Facebook, tasked with allowing SQL queries over datasets generated by Hadoop, created Apache Hive, and, with it, the Hive table format, which specified how to view a collection of files as a single logical table. The Hive table format in turn allowed organizations to create data lakes, repositories that store structured and semi-structured data in their original format for analysis by a wide range of tools, and, later, data lakehouses, which aim to combine the benefits of data lakes and traditional data warehouses by storing structured data using data lake tools and technologies.

A key concept of the Hive table format is partitioning, a way of organizing files to reduce the amount of data that must be read to process a query. Taking the Drive Stats dataset as an example, we can partition the files by year and month, so that each file has a prefix of the form:

/drivestats/year={year}/month={month}/

For example:

/drivestats/year=2024/month=12/

With this partitioning scheme, a system processing a query for hard drive statistics for, say, December 12, 2024, need only retrieve files with the above prefix. You might be wondering, “Why not partition the data on day, also, to further reduce the number of files that must be retrieved?” The answer depends on the data volume and access patterns. It’s much more efficient to partition data into fewer large files than many small files, so overly granular partitioning can actually impair performance.

It’s worth mentioning that file formats and table formats are largely independent of each other. You can use Avro, Parquet, ORC, or even CSV files with the Hive table format.

For more detail on the Parquet file format, Hive table format, and partitioning, see the blog post, Storing and Querying Analytical Data in Backblaze B2.

“Iceberg, captain, dead ahead!”

While the Hive table format served the big data community well for several years, it had a number of shortcomings:

  • Every query incurs a file list (“list objects”, in S3 API terms) operation, which is particularly expensive with cloud object storage, both in terms of time and API transaction charges.
  • Deleting or modifying data typically implies rewriting an entire data file, even if only a single row was affected.
  • Hive can only partition datasets on columns that are in the table schema. For example, the Drive Stats data set includes a date column, so to use it with Hive, we had to create additional, redundant, year and month columns.
  • Any changes to the data schema or partitioning strategy require affected files to be rewritten, making schema evolution problematic, if not infeasible, for large datasets.
  • There is limited support for the kind of ACID (Atomic, Consistent, Isolated, Durable) transactions that are familiar from the RDBMS world. Attempts to add transaction support to Hive were not widely or consistently supported.

As a result, vendors and the broader big data community formed a number of projects to define new table formats to succeed Hive, including Apache Iceberg, Apache Hudi, and Delta Lake, a Linux Foundation project.

The three are broadly comparable in terms of features, but, over the past couple of years, Iceberg has emerged as the leader in terms of vendor adoption, with Snowflake announcing general availability of Iceberg tables in June 2024, and Amazon announcing S3 Tables, its managed Iceberg offering, in December 2024. Significantly, Databricks, the prime mover behind Delta Lake, acquired Tabular, a company founded by the original creators of Apache Iceberg, in June 2024, establishing its own beachhead in the Iceberg community.

Iceberg‘s features allow it to be used to organize huge data sets, efficiently and flexibly:

  • Table metadata including the list of files that comprise a table is stored as JSON data alongside the data files, eliminating the need to run an expensive list object operation for every query.
  • Schema evolution allows you to add, drop, update, or rename columns.
  • Hidden partitioning decouples partitioning from the table schema. For example, you can partition data like the Drive Stats dataset by year and month based on the existing date values, without creating additional columns.
  • Partition layout evolution allows you to modify your partitioning strategy as data volume or access patterns change.
  • Time travel allows you to query table snapshots.
  • Serializable isolation provides atomic table changes, ensuring readers never see inconsistent data.
  • Multiple concurrent writers use optimistic concurrency, retrying to ensure that compatible updates succeed while detecting conflicting writes.

Iceberg is widely supported across the big data ecosystem, with many applications and tools  allowing you to store Iceberg tables in S3 compatible cloud object storage such as Backblaze B2. In this article, I’ll look at the simplest use case, running queries against the Drive Stats dataset, with three representative examples: Snowflake, Trino, and DuckDB.

Writing Iceberg data to Backblaze B2

I wrote a simple Python application, drivestats2iceberg, using the PyIceberg library, that converts the Drive Stats dataset from the zipped CSV files we publish to Parquet files in an Iceberg table stored in a Backblaze B2 Bucket. There are some useful techniques in drivestats2iceberg, and it is published on GitHub as open source, under the MIT license, so feel free to use it as a starting point for your own data conversion apps.

Querying Iceberg tables in Backblaze B2 from Snowflake

Snowflake is a data-as-a-service platform addressing a wide variety of use cases, including artificial intelligence (AI), machine learning (ML), collaboration across organizations, and data lakes.

A decorative image showing the Backblaze and Snowflake logos superimposed over a cloud that dissolves into binary 0s and 1s.
We’re big fans of the Backblaze + Snowflake integration. Our customers are too.

As I mentioned above, Snowflake announced general availability of its Iceberg tables offering in June 2024, allowing you to manipulate Iceberg tables located on external volumes, outside your Snowflake warehouse, and query them alongside data in Snowflake-managed tables.

Snowflake’s Iceberg implementation is quite complicated, with different capabilities according to your choice of cloud object storage provider and whether you want Snowflake to manage your Iceberg catalog or use a catalog integration.

For our simple use case, where the Iceberg metadata and data files already exist in a Backblaze B2 Bucket, the first step is to create a Snowflake external volume, configuring it with suitable credentials and the location of the Drive Stats data.

Note: the application key shown in this Snowflake statement has read-only access to the drivestats-iceberg bucket. You can use it to query the Drive Stats data set from your own Snowflake instance or from other environments.

CREATE EXTERNAL VOLUME drivestats_b2
STORAGE_LOCATIONS = (
(
NAME = 'b2_storage_location'
STORAGE_PROVIDER = 'S3COMPAT'
STORAGE_BASE_URL = 's3compat://drivestats-iceberg/'
CREDENTIALS = (
AWS_KEY_ID = '0045f0571db506a0000000017'
AWS_SECRET_KEY = 'K004Fs/bgmTk5dgo6GAVm2Waj3Ka+TE'
)
STORAGE_ENDPOINT = 's3.us-west-004.backblazeb2.com'
)
)
ALLOW_WRITES = FALSE;

Next, you must create a catalog integration. The object store catalog integration simply reads Iceberg metadata from an external (to Snowflake) cloud storage location:

CREATE CATALOG INTEGRATION my_iceberg_catalog_integration
CATALOG_SOURCE = OBJECT_STORE
TABLE_FORMAT = ICEBERG
ENABLED = TRUE;

Now you can create an Iceberg table object that references the existing dataset. Note that Snowflake requires you to explicitly specify the metadata file to use for column definitions; this is typically the most recently created JSON file under the metadata prefix.

CREATE ICEBERG TABLE drivestats
EXTERNAL_VOLUME = 'drivestats_b2'
CATALOG = 'my_iceberg_catalog_integration'
METADATA_FILE_PATH = 'drivestats/metadata/00225-317608b1-35a6-4135-8393-7543583623db.metadata.json';

That done, you can start querying the data:

How many records are in the current Drive Stats dataset?

SELECT COUNT(*) 
FROM drivestats;

Result:

564566016

How many hard drives was Backblaze spinning on a given date?

SELECT COUNT(*) 
FROM drivestats
WHERE date = DATE '2024-12-31';

Result:

305180

How many exabytes of raw storage was Backblaze managing on a given date?

SELECT ROUND(SUM(CAST(capacity_bytes AS BIGINT))/1e+18, 2) 
FROM drivestats
WHERE date = DATE '2024-12-31';

Result:

4.42

What are the top 10 most common drive models in the dataset?

SELECT model, COUNT(DISTINCT serial_number) AS count 
FROM drivestats
GROUP BY model
ORDER BY count DESC
LIMIT 10;

Results (in drive days):

TOSHIBA MG08ACA16TA   40859
TOSHIBA MG07ACA14TA 39387
ST12000NM0007 38843
ST4000DM000 37040
ST16000NM001G 34501
WDC WUH722222ALE6L4 30148
WDC WUH721816ALE6L4 26547
ST12000NM0008 21028
HGST HMS5C4040BLE640 16349
ST8000NM0055 15680

My x-small Snowflake warehouse executed the first three queries in a fraction of a second. As you might expect from its additional complexity, the last query took longer: 16 seconds.

Querying Iceberg tables in Backblaze B2 from Trino

Trino is an open-source distributed query engine, formerly known as PrestoSQL. Trino can natively query data in Backblaze B2, Cassandra, MySQL, and many other data sources without copying that data into its own dedicated store. Trino has become the Backblaze Evangelism Team’s go-to date lake tool over the past few years; we’ve used it in several past blog posts, and we maintain a GitHub repository with quick start guides for running Trino with BackblazeB2.

To access the Drive Stats data set from Trino, you must configure its Iceberg connector with a catalog properties file. For example, to configure a catalog named drivestats_b2, create a file etc/catalog/drivestats_b2.properties:

connector.name=iceberg

hive.metastore.uri=thrift://hive-metastore:9083

iceberg.register-table-procedure.enabled=true

fs.native-s3.enabled=true

s3.endpoint=https://s3.us-west-004.backblazeb2.com
s3.region=us-west-004
s3.aws-access-key=0045f0571db506a0000000017
s3.aws-secret-key=K004Fs/bgmTk5dgo6GAVm2Waj3Ka+TE
s3.exclusive-create=false

Note that the above configuration file uses the same read-only credentials as the Snowflake example. You can use this configuration file as-is to explore the Drive Stats dataset using Trino.

Start the Trino server and CLI, then create a Trino schema with the location of the data, and set it as the default schema for subsequent queries:

CREATE SCHEMA drivestats_b2.ds_schema
WITH (location = 's3://drivestats-iceberg/');
USE drivestats_b2.ds_schema;

The Trino Iceberg connector provides the register_table procedure for registering existing Iceberg tables into the metastore. Optionally, you can provide an additional metadata_file_name parameter if you wish to register the table with some specific table state, or if the connector cannot automatically figure out the metadata version to use.

CALL drivestats_b2.system.register_table(
schema_name => 'ds_schema',
table_name => 'drivestats',
table_location => 's3://drivestats-iceberg/drivestats'
);

Since you can query the table using the exact same SQL queries as in the Snowflake example, producing the exact same results, I won’t reproduce them here. Running Trino in a Docker container on my MacBook Pro, the first three queries executed in less than three seconds, the fourth took just over a minute.

Querying Iceberg tables in Backblaze B2 from DuckDB

DuckDB is an open-source column-oriented RDBMS, intended for in-process use: embedded in applications. There are DuckDB client APIs (also known as drivers) for many programming languages, including Python, Java, JavaScript (Node.js) and Go.

DuckDB is focused on the same kinds of use cases as Snowflake and Trino; it is effectively the OLAP equivalent to SQLite, which targets online transaction processing (OLTP) workloads.

To work with Iceberg tables in cloud object storage, you must install and load the httpfs and iceberg DuckDB extensions:

INSTALL httpfs;
LOAD httpfs;

INSTALL iceberg;
LOAD iceberg;

Now, you need to create a secret with your Backblaze B2 credentials.

Again, the application key shown here has read-only access to the Drive Stats dataset; you can use it to explore the data yourself if you like.

CREATE SECRET secret (
TYPE s3,
KEY_ID '0045f0571db506a0000000017',
SECRET 'K004Fs/bgmTk5dgo6GAVm2Waj3Ka+TE',
REGION 'us-west-004',
ENDPOINT 's3.us-west-004.backblazeb2.com'
);

By default, queries against Iceberg tables in DuckDB use a SELECT ... FROM iceberg_scan(...) syntax, but you can define a schema and a view so that you can use the same SQL queries as with Snowflake and Trino:

First, a schema:

CREATE SCHEMA ds_schema;
USE ds_schema;

Then, a view:

CREATE VIEW drivestats AS 
SELECT *
FROM iceberg_scan(
's3://drivestats-iceberg/drivestats',
version = '?',
allow_moved_paths = true
);

Note: the version = '?' parameter tells DuckDB to examine the table’s metadata files and “guess” which one corresponds to the latest version. This behavior is not enabled by default, so you must set unsafe_enable_version_guessing to true before you query the data, like this:

SET unsafe_enable_version_guessing = true;

That done, you can query the table using the exact same SQL queries as with Snowflake and Trino, with the exact same results. With DuckDB on my MacBook Pro, the first three queries took about 15–25 seconds; the fourth about 90 seconds.

Note that Snowflake, Trino and DuckDB are very different systems, with different trade-offs between cost, performance, and flexibility. I’ve included the execution times I saw to set your expectations when working with these tools, rather than as a point of comparison between them.

What’s next for Apache Iceberg?

Apache Iceberg is much more than a table format specification; it’s a broad, thriving ecosystem that is constantly innovating new features, tracking progress via its own GitHub repository. Here are a few technologies that are currently in active development:

  • Variant Data Type Support will offer a more efficient, versatile approach to managing hierarchical, JSON-like data, aligning with Apache Spark’s variant format.
  • Materialized Views will allow you to define a view as you usually would, in terms of a query against one or more existing views or tables, that is able to store data, like a table. On creation, the materialized view is populated with data and functions as a cache, serving its data in response to queries. The materialized view can be periodically refreshed to keep it in sync with its sources.
  • Geospatial Support will add Iceberg-native data types and operations storage and analysis of geospatial data, allowing you to define columns as points, lines and polygons, and use conditions such as “intersects” in queries.

I’ve only scratched the surface of Apache Iceberg in this blog post. Stay tuned for deeper dives into using Snowflake, Trino, DuckDB and more platforms and tools with the Iceberg table format and Backblaze B2 Cloud Storage.

The post Iceberg on Backblaze B2 appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Analyzing Performance at Exabyte Scale

Post Syndicated from Tim Johnson original https://www.backblaze.com/blog/analyzing-performance-at-exabyte-scale/

A decorative image showing a cloud in the foreground and various mocked up graphs in the background.

When you’re operating a data storage platform at exabyte scale, even small inefficiencies become big problems. With billions of files flowing through our systems, performance isn’t something we think about after the fact—it’s something we constantly chase, measure, and optimize.

But before you can improve cloud performance, you have to know where to look. When we were working on improving small file uploads, I was tasked with taking a closer look at our file upload pipeline to see if we could make it faster. 

The path from that general idea to hitting a clear performance goal taught me a lot—not just about our systems, but about how to approach performance work in a principled, strategic way. Here’s how it unfolded, and what you can apply to your own environment.

Step one: Define the problem

The initial ask from our Product team was pretty familiar: “Can we make uploads faster?” It’s a fair question, but not a very actionable one. So we worked with our Product team to define our success criteria. Here are some of the questions we asked to get to specific, actionable goals:

“What do we mean by faster? Do we want to improve latency or throughput?”

“Do we want to improve all uploads? Just big files? Just small files?
“What qualifies as a small upload?”

After some back and forth, we landed on a clear, measurable target: Process file uploads of 1MB or less via our B2 API in under 40 milliseconds. That specificity made a huge difference:

  • With a goal of 40 milliseconds, we had a stopping point. We would know when we’d done enough.
  • We had a bar to measure against and a way to identify what was worth optimizing. If something took two milliseconds, we could leave it alone. If it took 30, it became the focus.
  • We could scope effort. There’s a big difference between getting something under 40 milliseconds versus 200. 

Step two: Use the right tools for the job if you possibly can

Analyzing performance without proper tooling means doing a lot of heavy lifting by hand. We had to drop custom instrumentation throughout the stack, create metric-collecting objects, and pass them all the way down the call stack so we could get timing data from different parts of the upload path.

The upload flow touches more than 20 storage pods and services, so we also built a lightweight sampling system to keep from flooding our metrics pipeline. The data went into an open-source search and analytics suite, and from there we built dashboards to try to make sense of it all.

It was time-consuming. Painfully so. But it worked. 

I could now compare fast and slow uploads, identify patterns, and—most importantly—see where time was actually being spent. That’s how we discovered that fsync was dominating our performance profile, captured in the screenshot below. We measured each sub-operation that comprises our drive write operations, and grouped them by the total time they took to complete. You can see the process fsync sub-operation dominates in every group. Removing or optimizing around it offered a 10x speedup. But it took weeks of manual effort to get to that insight.

Drive write operations grouped by the time they took to complete.

Enter: Tracing at scale

Eventually, we brought in more powerful tooling, including an open source distributed tracing system. It was a game changer.

What used to take dozens of lines of code and a lot of custom wiring now took a single annotation. More importantly, it gave us something we couldn’t get otherwise: a way to see activity across services, systems, and pods—all in one view.

It allowed us to correlate events happening across different physical machines, trace performance end-to-end, and understand the impact of specific changes in real time.

At one point, we were debating whether a particular optimization would get us across the finish line. This optimization allows the slowest shard to store asynchronously if and only if all others had been successfully and durably stored. This prevents a single slow shard from slowing down the entire upload. Thanks to the new tooling, we didn’t have to guess—we could see that once we flipped the switch, we’d hit our 40ms goal (and it would help all other uploads as well, not just small uploads). That let us focus on getting that one feature ready for production, confident that it would move the needle.

Visualization demonstrating one of our upload optimizations, this time for a slower upload. The first 19 shards to complete were stored successfully and durably, so we stop waiting for the last shard, return a 200 status code to the customer (indicated by the dotted line), and allow the 20th shard to finish asynchronously.

Step three: Optimize with intent

One of the biggest lessons I learned through this process is that you can spend weeks optimizing the wrong thing if you’re not careful. That’s why measurement has to come first.

Don’t guess. Instrument. Don’t tweak randomly. Set a baseline and track deltas. Performance work is iterative. You’ll fix one bottleneck, only to reveal the next one lurking beneath it. That’s the job.

In hindsight, one of the smartest things we did was setting a clear performance goal at the start of the project. It didn’t just help us focus—it told us when we were done. You can optimize forever. Knowing when to stop is just as important as knowing where to begin.

Step four: Tool up for the future

The tracing tool has made life a lot easier, but it’s not the only tool we use. Our analytics suite still plays a big role when we want to analyze aggregate data, or need the flexibility to slice and dice data. The two complement each other nicely.

There’s no one-size-fits-all solution—it’s more like a toolbox. And like any good toolbox, it keeps growing with our needs.

Advice from the trenches

If you’re running distributed systems or chasing performance in your own stack, here’s what I’d suggest:

  • Start with a clear goal. Know exactly what “faster” means, and write it down.
  • Measure before you optimize. Otherwise, you’re flying blind.
  • Pick the right tool for the job. Tracing, metrics, logs—they all have their place.
  • Don’t wait to build your tools. Invest in observability early.
  • Know when to stop. The ROI of performance work diminishes fast if you’re not careful.

And maybe give your helper methods better names than DoSomeWork. Or don’t. It makes the code reviews a little more entertaining.

The post Analyzing Performance at Exabyte Scale appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

What Powers the Performance of Backblaze

Post Syndicated from Tina Cessna original https://www.backblaze.com/blog/what-powers-the-performance-of-backblaze/

A decorative image showing objects around the cloud.

At Backblaze, we’re in the business of building a storage platform that can handle billions of operations a day—reliably, predictably, and fast. That means digging deep into low-level architecture, optimizing what most people overlook, and constantly balancing trade-offs between performance, cost, and scale.

Today, we’re kicking off a new blog series that showcases the platform-level work our Engineering team has been doing to build and run a modern cloud storage platform. The kind of work that usually stays buried in Jira tickets and internal docs, but that makes all the difference when you’re serving exabytes at scale.

What it really means to build a modern cloud storage platform

When people talk about cloud storage, they usually focus on capacity, availability, and price. This includes the systems, tools, and architectural decisions that enable our infrastructure to scale reliably while handling billions of operations per day.

We’re crafting a dynamic, evolving platform that handles exabytes of data with reliability and efficiency. We’re a platform that developers and businesses build on. That means durability, performance, uptime, and predictability aren’t just nice-to-haves—they’re fundamental requirements. As Senior Vice President of Engineering, I’m excited to pull back the curtain and offer a glimpse into the ongoing engineering efforts that power our platform.

Building for simple is more complex than it seems

One of our core engineering philosophies is this: Complexity should serve simplicity. For example, changing how we handle request headers might sound like a small thing, but when you operate a distributed system at scale, even tiny inefficiencies can multiply quickly. A 5% improvement in API response time might not sound dramatic, but at exabyte scale, that translates to millions of faster interactions per day, less CPU usage, and better customer experiences across the board.

Our Engineering team is always thinking about those compound effects. Sometimes that means rewriting parts of a system that have been stable for years. Other times it means saying no to flashy solutions and choosing battle-tested designs that will hold up under load.

What to expect from this series

If you care about performance, distributed architecture, or what it actually takes to run a reliable cloud infrastructure, this is for you. We’ve published deep dives before, such as our articles on Load Balancing (and Load Balancing 2.0!), improvements on small file uploads that gave us speeds faster than AWS, Network Stats, Reed-Solomon erasure coding, using native code in Backblaze Personal Backup, everything that lives in the Backblaze Github, and many, many more. 
Our goal, in addition to talking about the individual stories, is to start talking about some of the throughlines—when one project spawns another, or how we decide which project to pursue when there are competing priorities. 

These projects don’t usually make headlines on their own, but taken together, they form the backbone of what makes Backblaze perform the way it does. They’ll become part of our regularly scheduled programming, and we’ll drop them in our Tech Lab category so you can find them easily.

Sign up for the Developer newsletter

Sign up for the Backblaze Developer Newsletter to receive a monthly roundup of articles and news for everyone developing on Backblaze B2 Cloud Storage.

Sign Up Here ➔ 

See you on the next one—and let us know if you have questions

We’re proud of the work our engineers are doing, but more than that, we think it’s worth sharing. Whether you’re a fellow cloud architect, a developer using our platform, or just someone curious about what it takes to run cloud infrastructure at scale, we hope this series offers something insightful. 

Technology doesn’t stand still, and neither do we. The more efficient our platform becomes, the better we can serve our customers—and the more we can invest in new ideas. So stay tuned. We’re kicking things off in this content series in the next few weeks, and we look forward to hearing your thoughts!

The post What Powers the Performance of Backblaze appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Experimenting with DeepSeek, Backblaze B2, and Drive Stats

Post Syndicated from Pat Patterson original https://www.backblaze.com/blog/experimenting-with-deepseek-backblaze-b2-and-drive-stats/

A decorative image showing buildings of many sizes.

As we explained in our recent blog post, AI Reasoning Models: OpenAI o3-mini, o1-mini, and DeepSeek R1, Chinese startup DeepSeek caused a stir when it released its R1 reasoning model in January of this year. Interestingly, DeepSeek R1 has an OpenAI-compatible API, so applications written for OpenAI should work with DeepSeek R1 with just a configuration change. Since I had a suitable sample app all ready to go, I decided to put their claim to the test.

Why, and why not, use DeepSeek?

A major difference between DeepSeek and OpenAI is cost. At the time of writing, DeepSeek charges $0.55 per million input tokens and $2.19 per million output tokens for its R1 model. That’s about 3.6% of OpenAI’s $15.00 per million input tokens and $60.00 per million output tokens for its flagship o1 reasoning model, and about half of o3-mini’s $1.10 per million input tokens and $4.40 per million output tokens.

Set against this is the fact that, in using the DeepSeek platform’s API, you are sending your data to a startup located in China that has been accused by OpenAI of “inappropriately” basing its work on the output of OpenAI’s models. It’s up to you, and your organizations’ data governance policy, whether the trade-off is worthwhile.

Another consideration is the ability to run DeepSeek’s models locally, on your own infrastructure, or, more likely, your chosen provider’s infrastructure, rather than sending requests to the DeepSeek platform. Spinning up my own DeepSeek instance was out of scope for this blog post, but I’ll likely return to it in a future blog post.

Swapping OpenAI for DeepSeek

Last month, I explained how you can build an AI agent with Backblaze B2, LangChain, and Drive Stats, walking you through a simple chatbot that can answer questions based on our Drive Stats data set—11 years of metrics gathered from the Backblaze B2 Cloud Storage platform’s fleet of hard drives. In that example, the chatbot accepted a natural language question, used OpenAI’s GPT‑4o mini large language model (LLM) to generate a SQL query that might help provide an answer, executed the query against the Drive Stats data set via the Trino SQL engine, and then used OpenAI again to interpret the result set and either repeat the query-interpret cycle, or generate a natural language answer.

I copied the Jupyter notebook from that example and used it as the basis for investigating the feasibility of swapping out OpenAI for DeepSeek. The DeepSeek version of the notebook contains the full source code of my experiments; I’ll include relevant extracts here, edited for clarity.

Since I used the LangChain AI framework, which provides a layer above a range of AI models, the only place that OpenAI surfaced in my code was in creating an instance of LangChain’s ChatOpenAI wrapper:

# OPENAI_API_KEY must be defined in the .env file
load_dotenv()
llm = ChatOpenAI(model="gpt-4o-mini")

The ChatOpenAI class contains all the code required to communicate with OpenAI via its API.

According to the DeepSeek documentation, all you should need to do is:

  • Provide your DeepSeek API key in the same OPENAI_API_KEY environment variable.
  • Set the API base URL to https://api.deepseek.com.
  • Provide a DeepSeek model name in place of the OpenAI one.

If this reminds you of the steps for using Backblaze B2’s S3-compatible API, you’re not alone. The OpenAI API has become a de facto standard for integrating with LLMs in much the same way as Amazon’s S3 API allows an ecosystem of apps and tools to interoperate with object storage systems from a variety of vendors.

Looking at the DeepSeek documentation, you can use one of two models, deepseek-reasoner (aka DeepSeek R1) or deepseek-chat. Let’s see what the much-talked-about DeepSeek R1 came up with.

Using DeepSeek R1 in the AI agent

To make it easy to use both the OpenAI and DeepSeek notebooks, I created a second entry in the .env file for the DeepSeek API key, and copied it to the OpenAI environment variable in the notebook code:

# The .env file needs at least DEEPSEEK_API_KEY, and may also contain
# OPENAI_API_KEY. Move the DeepSeek API key to the OpenAI environment
# variable
load_dotenv()

os.environ["OPENAI_API_KEY"] = os.environ.pop("DEEPSEEK_API_KEY")

llm = ChatOpenAI(model="deepseek-reasoner", base_url='https://api.deepseek.com')

As I set about repeating the steps from the Jupyter notebook that supported my previous blog post, I was disappointed to see DeepSeek fall at the very first hurdle: generating a SQL query for a simple natural language question. Here is the code:

question = {"question": "How many drives are there?"}

write_query(question)

Looking back at the original notebook, OpenAI’s response was valid SQL, although it didn’t have enough information to construct the correct query:

{'query': 'SELECT COUNT(*) AS drive_count FROM drivestats'}

DeepSeek, on the other hand, responded with a Python stack trace and this error:

openai.UnprocessableEntityError: Failed to deserialize the JSON body into the target type: response_format: response_format.type `json_schema` is unavailable now at line 1 column 13827

What went wrong? Searching for the error turns up a comment from a LangChain engineer explaining that we should use BaseChatOpenAI rather than ChatOpenAI since it “[…] accommodates many APIs that are similar to OpenAI. It uses tool calling for structured output by default.”

So, we can redefine llm accordingly, and try generating a query again:

llm = BaseChatOpenAI(model="deepseek-reasoner", base_url='https://api.deepseek.com')

write_query(question)

Unfortunately, DeepSeek returns another error:

BadRequestError: Error code: 400 - {'error': {'message': 'The last message of deepseek-reasoner must be a user message, or an assistant message with prefix mode on (refer to https://api-docs.deepseek.com/guides/chat_prefix_completion).', 'type': 'invalid_request_error', 'param': None, 'code': 'invalid_request_error'}}

Looking back at the AI agent code, we can see that we used an off-the-shelf prompt from the LangChain Prompt Hub that provides the model with a single, system, message:

================================ System Message ================================

Given an input question, create a syntactically correct {dialect} query to run to help find the answer. Unless the user specifies in his question a specific number of examples they wish to obtain, always limit your query to at most {top_k} results. You can order the results by a relevant column to return the most interesting examples in the database.

Never query for all the columns from a specific table, only ask for a few relevant columns given the question.

Pay attention to use only the column names that you can see in the schema description. Be careful to not query for columns that do not exist. Also, pay attention to which column is in which table.

Only use the following tables:
{table_info}

Question: {input}

Does this mean that DeepSeek is not, in fact, API-compatible with OpenAI? I would argue that it does not. DeepSeek implements the same API request/response syntax as OpenAI, but it is a different platform. Some variation in semantics is to be expected. We see similar variations between Backblaze B2 and Amazon S3; for example, the S3 PutObjectAcl operation sets the access control list (ACL) for an object in a bucket. Amazon S3’s access management model allows you to manipulate an object’s ACL independently of its bucket—for example, you can put a private object in a public bucket, and vice versa.

This flexibility comes with a cost: It becomes difficult to reason about the visibility of data. In fact, AWS now recommends “that you keep ACLs disabled, except in unusual circumstances where you need to control access for each object individually.”

Backblaze B2’s model is much simpler: You control access at the bucket level, and all objects have the same ACL as their bucket. Backblaze B2 implements the PutObjectAcl operation, but, if you try to set an object’s ACL to any other value than its bucket’s ACL, the service responds with an error.

Returning to the AI agent code, we can replace the single-system-message prompt with one that combines a system message with a user message:

import textwrap
from langchain_core.prompts import ChatPromptTemplate

query_prompt_template = ChatPromptTemplate([
("system", textwrap.dedent("""Given an input question, create a
syntactically correct {dialect} query to run to help find the answer.
Unless the user specifies in his question a specific number of examples
they wish to obtain, always limit your query to at most {top_k} results.
You can order the results by a relevant column to return the most
interesting examples in the database.

Never query for all the columns from a specific table, only ask for a the
few relevant columns given the question.

Pay attention to use only the column names that you can see in the schema
description. Be careful to not query for columns that do not exist. Also,
pay attention to which column is in which table.

Only use the following tables:
{table_info}""")),
("human", "Question: {input}"),
])

Trying the write_query() call for a third time, this is the response:

BadRequestError: Error code: 400 - {'error': {'message': 'deepseek-reasoner does not support Function Calling', 'type': 'invalid_request_error', 'param': None, 'code': 'invalid_request_error'}}

A third error! What is this “function calling” that deepseek-reasoner does not support? A helpful article on the topic at the Hugging Face AI community explains:

Function calling is a powerful capability that enables Large Language Models (LLMs) to interact with your code and external systems in a structured way. Instead of just generating text responses, LLMs can understand when to call specific functions and provide the necessary parameters to execute real-world actions.

Unfortunately, that is exactly our use case. It’s becoming clear that DeepSeek R1 is not the correct tool for implementing an AI agent—we’ve been trying to use a chisel as a screwdriver!

DeepSeek-V3: A better fit

As its name suggests, the deepseek-chat model is more appropriate for this application. The DeepSeek documentation tells us that it is based on DeepSeek-V3, released in December 2024. DeepSeek-V3 is priced at $0.27 per million input tokens and $1.10 per million output tokens; this is actually more expensive than the GPT-4o mini model I used for the OpenAI agent example ($0.15 per million input tokens, $0.600 per million output tokens), but how does it compare? Let’s take a look.

First, we need to edit the LLM creation code again to set the model name:

llm = BaseChatOpenAI(model="deepseek-chat", base_url='https://api.deepseek.com')

Now we can run write_query() again. It’s immediately clear that it’s a better fit than its “big brother:”

{'query': 'SELECT COUNT(*) AS total_drives FROM drivestats LIMIT 10'}

As with the OpenAI agent, this query is well-formed SQL, but it’s not answering the question we set—it’s giving us the total number of rows in the dataset, rather than the number of drives. Also, it’s a little odd to have a LIMIT clause in a SELECT COUNT(*) query, but it’s legal SQL, and the agent is following its instructions very literally: always limit your query to at most {top_k} results, where we set top_k to 10.

question = {"question": "Each drive has its own serial number. How many drives are there?"}

query = write_query(question)

{'query': 'SELECT COUNT(DISTINCT serial_number) AS total_drives FROM drivestats'}

So far, so good!

I’ll skip some intermediate steps here—they are all in the Jupyter notebook if you want to review them, or run them for yourself—and look at how a simple LangChain graph, built on the DeepSeek LLM, answered the question: “Each drive has its own serial number. How many drives did each data center have on 9/1/2024?”

The OpenAI version generated an invalid query, comparing the date column with the string ’2024-09-01’ without using the required DATE type identifier, but DeepSeek generates a correct SQL query and provides a useful natural language response:

/SELECT datacenter, COUNT(DISTINCT serial_number) AS drive_count FROM drivestats WHERE date = DATE ‘2024-09-01’ GROUP BY datacenter ORDER BY drive_count DESC LIMIT 10


[(‘phx1’, 89477), (‘sac0’, 78444), (‘sac2’, 60775), (”, 24080), (‘iad1’, 22800), (‘ams5’, 16139)]


On September 1, 2024, the data centers had the following number of drives:

  • phx1: 89,477 drives
  • sac0: 78,444 drives
  • sac2: 60,775 drives
  • (empty datacenter): 24,080 drives
  • iad1: 22,800 drives
  • ams5: 16,139 drives

These are the top data centers with the highest drive counts on that date.

DeepSeek scores a point!

Moving on to the ReAct AI Agent, which allows the LLM to perform multiple SQL queries in generating an answer to a question, DeepSeek performs similarly to OpenAI. Given the question, “Each drive has its own serial number. What is the annualized failure rate of the ST4000DM000 drive model?”, the DeepSeek agent provides the overall failure rate rather than the annualized failure rate (AFR).

When we provide explicit instructions for calculating AFR in its prompt, the DeepSeek agent provides the correct result, identical, in fact, to the OpenAI agent’s response:

The annual failure rate (AFR) for the ST4000DM000 drive model is approximately 2.63%.

However, when given the question, “What was the annual failure rate of the ST8000NM000A drive model in Q3 2024?”, the DeepSeek agent gives us:

[(1.6100573445081607,)]

While OpenAI responds:

The annual failure rate (AFR) of the ST8000NM000A drive model in Q3 2024 is approximately 1.61%.

Wrapping up the investigation, the final question from the OpenAI notebook is more complex:

Considering only drive models which had at least 100 drives in service at the end of the quarter and which accumulated 10,000 or more drive days during the quarter, which drive had the most failures in Q3 2024, and what was its failure rate?

Impressively, the OpenAI agent constructed a well-formed SQL query and provided the correct response:

The drive model with the most failures in Q3 2024 is the TOSHIBA MG08ACA16TA, which had 181 failures. Its failure rate during this period was approximately 1.84%.

BadRequestError: Error code: 400 - {'error': {'message': "An assistant message with 'tool_calls' must be followed by tool messages responding to each 'tool_call_id'. (insufficient tool messages following tool_calls message)", 'type': 'invalid_request_error', 'param': None, 'code': 'invalid_request_error'}}
During task with name 'agent' and id '0aa26ba6-a3ee-ced1-de4d-b60ed7fbca99'

The phrase “insufficient tool messages” suggested that the DeepSeek LLM might need to be reconfigured to allow more tokens. According to the documentation on models and pricing, the deepseek-chat model supports a maximum of 8K output tokens, but defaults to 4K if max_tokens is not specified.

Recreating the DeepSeek wrapper object and agent accordingly, I gave it the last question again:

llm = BaseChatOpenAI(model="deepseek-chat", base_url='https://api.deepseek.com', max_tokens=8192, **extra_kwargs)

agent_executor = create_react_agent(llm, tools, state_modifier=system_message)

response = agent_executor.invoke(
{"messages": [{"role": "user", "content": "Considering only drive models which had at least 100 drives in service at the end of the quarter and which accumulated 10,000 or more drive days during the quarter, which drive had the most failures in Q3 2024, and what was its failure rate?"}]}
)

# Show the SQL query sent to the database
print(response['messages'][-3].tool_calls[0]['args']['query'])

# Show the final response message
display_markdown(response['messages'][-1].content, raw=True)

This time, DeepSeek was able to generate a similar SQL query to OpenAI:

WITH drive_counts AS (
SELECT model, COUNT(DISTINCT serial_number) AS drive_count
FROM drivestats
WHERE date >= DATE '2024-07-01' AND date <= DATE '2024-09-30'
GROUP BY model
HAVING COUNT(DISTINCT serial_number) >= 100
), drive_days AS (
SELECT model, COUNT(*) AS total_drive_days
FROM drivestats
WHERE date >= DATE '2024-07-01' AND date <= DATE '2024-09-30'
GROUP BY model
HAVING COUNT(*) >= 10000
), failures AS (
SELECT model, COUNT(*) AS failure_count
FROM drivestats
WHERE date >= DATE '2024-07-01' AND date <= DATE '2024-09-30' AND failure = 1
GROUP BY model
)
SELECT d.model,
f.failure_count,
100 * (CAST(f.failure_count AS DOUBLE) / (CAST(d.total_drive_days AS DOUBLE) / 365)) AS annual_failure_rate
FROM drive_days d
JOIN failures f ON d.model = f.model
JOIN drive_counts dc ON d.model = dc.model
ORDER BY f.failure_count DESC
LIMIT 1

With a correct response:

To answer the question:

The drive model with the most failures in Q3 2024 is TOSHIBA MG08ACA16TA, which had 181 failures. The annualized failure rate (AFR) for this model during that quarter was 1.84%.

Success! But, unfortunately, this isn’t the whole story.

DeepSeek Reliability

A screenshot of a DeepSeek error message.

I originally set out to write this blog post at the end of January, but the DeepSeek platform website had gone offline by January 30, so I couldn’t even start until I was able to sign up for an API key on February 5.

A screenshot of DeepSeek availability from December 2024 to Feburary 2025.

Given my shiny new API key, and DeepSeek’s claims of OpenAI API compatibility, I naïvely expected to be able to work through my earlier OpenAI notebook and write up the results in a couple of days. The reality was more like two weeks.

In this blog post I’ve detailed some of the error messages I encountered along the way, but I saw many more that pointed to the DeepSeek API simply being overwhelmed with traffic. For example, for over a day, when the status page reported no issues, most API requests to DeepSeek terminated after a minute with the error message:

json.decoder.JSONDecodeError: Expecting value: line 1 column 1 (char 0)

A time-consuming investigation revealed that this was caused by the DeepSeek API returning the 200 status code and headers as if the request was successful, then hanging for a minute before terminating the connection without returning any actual data. The calling code saw the 200 as success and tried to decode the non-existent API response body, resulting in the error.

I saw several more instances of intermittent errors that all seemed to point in the same direction: DeepSeek needs to add capacity to its API platform. Notably, the platform seemed faster and more stable on a Saturday morning, U.S. Pacific time, the early hours of Sunday morning in China.

Final thoughts

At present, I would have to classify the DeepSeek-V3 API as “promising, but somewhat flaky.” An agent invocation that succeeds one minute could fail the next with any of a range of error messages. That’s a shame, since when it does work, for instance, in creating the SQL query for the final question above, it tends to work very well.

One final caveat: This is a dynamic field; frameworks and services are literally being updated on a daily basis. For example, since yesterday, as I write this, four of the notebook’s module dependencies have been updated. I encourage you to experiment for yourself as your mileage will almost certainly vary, hopefully in a positive direction.

The post Experimenting with DeepSeek, Backblaze B2, and Drive Stats appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Building an AI Agent with Backblaze B2, LangChain, and Drive Stats

Post Syndicated from Pat Patterson original https://www.backblaze.com/blog/building-an-ai-agent-with-backblaze-b2-langchain-and-drive-stats/

A decorative image showing multiple computer windows folding into the cloud.

Last August, I explained how you can use a Jupyter Notebook to explore AI development; specifically, building a chatbot that answers questions based on custom context downloaded from a private bucket in Backblaze B2 Cloud Storage. 

In this post, I’ll look at another AI technology, agents, and show you how I built an AI agent that answers questions about hard drive reliability based on over 11 years of raw data from our Drive Stats franchise. 

The Drive Stats dataset is ideal for this kind of work. It’s a real-world dataset, but, it only weighs in at around 500 million records consuming about 20GB of storage in Parquet format (“only” being a relative term), so you can use it with big data and AI tools on a laptop in a reasonable amount of time rather than spinning up an expensive virtual machine (VM) and/or spending days waiting for an operation to complete. As an example, converting the entire Drive Stats data set from CSV to Parquet using a Python app on my MacBook Pro takes a couple of hours. On the same hardware, converting a terabyte-scale data set would take about four days.

Speaking of Drive Stats

The Drive Stats 2024 report comes out February 11, and we’re hosting a LinkedIn Live event where Andy Klein, resident Drive Stats guru, will share highlights. Register today to save your spot.

Register Here ➔ 

You can use these same techniques with any large dataset, from healthcare to ecommerce to financial services. In this example, we’re working with a single table, but you could adapt the sample code to a data lake comprising any number of tables.

What is an AI agent?

In the spirit of the times, I posed this question to ChatGPT. Its answer:

An AI agent is a software system designed to autonomously perform tasks or make decisions based on its environment and goals. It leverages artificial intelligence techniques—such as machine learning, reasoning, and natural language processing—to process information, make decisions, and take actions to achieve specific objectives.
Key components of an AI agent include:

  1. Perception: The ability to sense and understand its environment. This could be through sensors, input data, or other means of gathering information.
  2. Reasoning/decision-making: The core processing mechanism that helps the agent interpret its environment, make decisions, and plan actions. It could use various algorithms, such as decision trees, reinforcement learning, or neural networks.
  3. Action: Once the agent has analyzed the environment and made a decision, it takes action to achieve its goal, whether it’s performing an operation, giving a recommendation, or interacting with another system.
  4. Learning: Some AI agents can adapt over time, improving their decision-making and actions based on experience (via reinforcement learning, supervised learning, etc.).

AI agents can range from simple systems, like chatbots or virtual assistants, to more complex systems like autonomous vehicles, robots, or financial trading algorithms.

In general, the term “agent” emphasizes the idea of autonomy—the agent operates independently, often with the ability to learn, adapt, and make decisions based on changing conditions without direct human intervention.

In this example, the agent’s environment is a database containing the Drive Stats data (more on that below), and I want it to perform the following tasks:

  • Based on a natural language question, such as “Which drive has the lowest annual failure rate?”, generate a SQL query that retrieves data that will help answer the question.
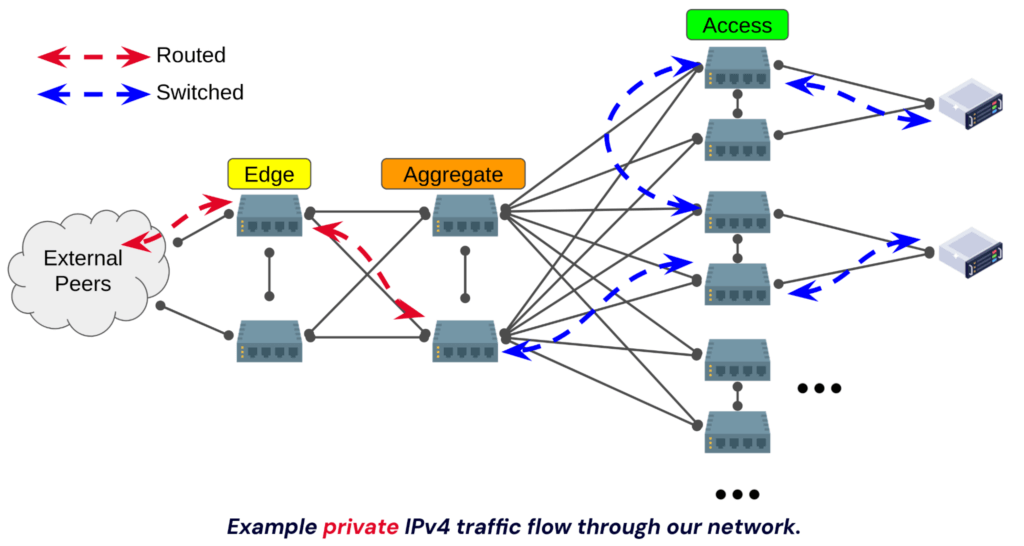
  • Execute that query against the Drive Stats dataset.
  • Based on the query results, either create a new query that better answers the question, or generate a natural language answer.

As in my previous post, I’m using the open source LangChain framework. This tutorial on building a question/answering system over SQL data was my starting point. I’ll explain key points of the integration in this blog post; the full source code is available as a Jupyter notebook in the ai-agent-demo repository.

Querying the Drive Stats dataset

Now I’ve established that my agent will be writing a SQL query, the next question is, “What will it be querying?” I’ve written about querying the Drive Stats dataset before; in that blog post I explained how I wrote a Python script to convert the Drive Stats data from the CSV format in which we publish it to Apache Parquet, a column-oriented file format particularly well-suited for storing tabular data for use in analytical queries, and upload it to a Backblaze B2 Bucket using the Apache Hive table format. There’s a broad ecosystem of tools and platforms that can manipulate Parquet data in object storage (for example, Apache Spark and Snowflake) and I chose Trino, the open source distributed SQL engine that forms the basis for Amazon Athena, to execute queries against the data.

I could have used the same technologies for this exercise, but I decided to add Apache Iceberg to the mix. While Parquet is a file format that specifies how tabular data is stored in files, Iceberg is a table format that governs how those files can be combined and interpreted as a database table. Iceberg provides a number of advantages over Hive as a table format, including better performance and much more flexible data partitioning.

What is partitioning?

Partitioning splits a dataset on one or more column values, easing data management and improving performance when a query includes a partition column.

Partitioning by year and month makes sense for the Drive Stats dataset—the resulting Parquet files are in the hundreds of megabytes, the sweet spot for Parquet data. To apply this partitioning to the Drive Stats data using the Hive table format, I had to create otherwise redundant month and year columns from the existing date column, complicating the schema.

Iceberg, by contrast, supports hidden partitioning, allowing you to apply a transformation to a column value to produce a partition value without adding any new columns. With the Drive Stats data, that meant I could simply define the partitioning as month(date) (the resulting value being the number of months since 1/1/1970, rather than an integer between 1 and 12), with no need to create any additional columns.

LangChain’s SQLDatabase class provides access to databases via the SQLAlchemy  open-source Python library. The demo code obtains a SQLDatabase instance by providing a URI containing the trino scheme, a username and the location of the database node:

db = SQLDatabase.from_uri('trino://admin@localhost:8080/iceberg/drivestats')

Note: In this and other code excerpts in this blog post, I’ve omitted extraneous “boilerplate” code. As mentioned above, the full source code is available in the ai-agent-demo repository.

As you can infer from the localhost domain name, I’m running Trino on my laptop. I’m actually running it in Docker, using the Iceberg/Hive Docker Compose script from the trino-getting-started-b2 repository. I’ll dive into that example in a future blog post.

A simple query confirms that we have a successful database connection:

db.run("SELECT COUNT(*) FROM drivestats")

'[(537220724,)]'

As the result conveys, there are over 537 million rows in the Drive Stats dataset.

Each row contains the metrics collected from a single drive in the Backblaze fleet on a specific day. The schema has evolved over time, but, currently, the following columns are included:

  • date: The date of collection.
  • serial_number: The unique serial number of the drive.
  • model: The manufacturer’s model number of the drive.
  • capacity_bytes: The drive’s capacity in bytes.
  • failure: 1 if this was the last day that the drive was operational before failing, 0 if all is well.
  • pod_slot_num: The physical location of a drive within a storage server, as an integer from 0 to 59. The specific slot differs based on the storage server type and capacity: Backblaze (45 or 60 drives), Dell (26 drives), or Supermicro (60 drives).
  • pod_id: There are 20 storage servers in each Backblaze Vault. The pod_id is a numeric field with values from 0 to 19 assigned to each of the 20 storage servers.
  • vault_id: All data drives are members of a Backblaze Vault. Each Vault consists of either 900 or 1,200 hard drives divided evenly across 20 storage servers. The Vault is a numeric value starting at 1,000.
  • cluster_id: The name of a given collection of storage servers logically grouped together to optimize system performance, formatted as a numeric field with up to two digits. Note: At this time the cluster_id is not always correct; we are working on fixing that.
  • datacenter: The Backblaze data center where the drive is installed, currently one of ams5 (Amsterdam, Netherlands), iad1 (Reston, Virginia), phx1 (Phoenix, Arizona), sac0 (Sacramento, California), sac2 (Stockton, California) or, now live, yyz1, our new Toronto, Ontario, data center.
  • is_legacy_format: Currently 0, but may change in future as more fields are added.
  • A collection of SMART attributes. The number of attributes collected has risen over time; currently we store 93 SMART attributes in each record, each one in both raw and normalized form, with field names of the form smart_n_normalized and smart_n_raw, where n is between 1 and 255.

Using OpenAI to generate a SQL query

For this project, I decided to use the OpenAI API, rather than running a large language model (LLM) directly on my laptop. LangChain has a chat model integration for OpenAI, as well as many other providers, so you could use, for example, a local Llama model (via ChatOllama) or one of the Claude models (via ChatAnthropic) if you prefer.

To use the OpenAI API, you must sign up for an OpenAI account and create an OpenAI API key. This code loads the API key from a .env file and creates a chat model instance using OpenAI’s GPT-4o mini model:

# OPENAI_API_KEY must be defined in the .env file
load_dotenv()
llm = ChatOpenAI(model="gpt-4o-mini")

Now we need a system prompt template. We’ll combine this with the database schema and a natural language question to form the prompt that we send to OpenAI. As in the LangChain tutorial, I’m using a prompt from the LangChain Prompt Hub:

query_prompt_template = hub.pull("langchain-ai/sql-query-system-prompt")
query_prompt_template.messages[0].pretty_print()

This is the prompt template text, with the placeholders shown in {braces}:

================================ System Message ================================

Given an input question, create a syntactically correct {dialect} query to run to help find the answer. Unless the user specifies in his question a specific number of examples they wish to obtain, always limit your query to at most {top_k} results. You can order the results by a relevant column to return the most interesting examples in the database.

Never query for all the columns from a specific table, only ask for a few relevant columns given the question.

Pay attention to use only the column names that you can see in the schema description. Be careful to not query for columns that do not exist. Also, pay attention to which column is in which table.

Only use the following tables:
{table_info}

Question: {input}

Notice how the template requires you to specify the correct SQL dialect, constrains the number of results returned, and encourages the model to not hallucinate column names that do not exist in the schema.

A helper function populates the prompt template, sends it to the model, and returns the generated SQL query:

def write_query(state: State):
    prompt = query_prompt_template.invoke(
        {
            "dialect": db.dialect,
            "top_k": 10,
            "table_info": db.get_table_info(),
            "input": state["question"],
        }
    )
    structured_llm = llm.with_structured_output(QueryOutput)
    result = structured_llm.invoke(prompt)
    return {"query": result["query"].rstrip(';')}

We can test the helper function by calling it directly with a Python dictionary containing a simple question:

question = {"question": "How many drives are there?"}
query = write_query(question)

The resulting query dictionary does indeed contain a valid SQL query, but it won’t give us the answer we are looking for.

{'query': 'SELECT COUNT(*) AS drive_count FROM drivestats'}

That query will tell us how many rows there are in the dataset, rather than how many drives. We supplied the database schema to the model, but we haven’t given it any information on the semantics of the columns in the drivestats table. We can provide a bit more detail to obtain the correct query:

question = {"question": "Each drive has its own serial number. How many drives are there?"}
query = write_query(question)

This time, the generated SQL query is correct:

{'query': 'SELECT COUNT(DISTINCT serial_number) AS total_drives FROM drivestats'}

As you can see, it’s important to check the output of AI models—they can and do generate unexpected results.

A second helper function executes the query against the database:

def execute_query(state: State):
    execute_query_tool = QuerySQLDatabaseTool(db=db)
    return {"result": execute_query_tool.invoke(state["query"])}

We can test it using the (correct) generated query:

result = execute_query(query)

{'result': '[(430464,)]'}

We need one more helper function, to pass the result set to the model and have it generate a natural language response. This time, we define our own prompt:

def generate_answer(state: State):
    prompt = (
        "Given the following user question, corresponding SQL query, "
        "and SQL result, answer the user question.\n\n"
        f'Question: {state["question"]}\n'
        f'SQL Query: {state["query"]}\n'
        f'SQL Result: {state["result"]}'
    )
    response = llm.invoke(prompt)
    return {"answer": response.content}

Again, we can test it in isolation. Notice that we have to provide the question and query, as well as the result so that the model has the context it needs:

answer = generate_answer(question | query | result)
answer['answer']

'There are 430,464 drives.'

Success! At the present time, there are indeed 430,464 drives in the Drive Stats dataset.

LangChain’s LangGraph orchestration framework allows us to compile our three helper functions into a single graph object:

graph_builder = StateGraph(State).add_sequence(
    [write_query, execute_query, generate_answer]
)
graph_builder.add_edge(START, "write_query")
graph = graph_builder.compile()

We can visualize the flow in the notebook:

display(Image(graph.get_graph().draw_mermaid_png()))
A diagram showing a query workflow. The workflow is defined as start, write_query, execute_query, generate_answer.

We’ve combined the write_query and execute_query steps into a graph object that can run agent-generated queries. I’ll quote the security note from the LangChain tutorial on the inherent risks in doing so:

Building Q&A systems of SQL databases requires executing model-generated SQL queries. There are inherent risks in doing this. Make sure that your database connection permissions are always scoped as narrowly as possible for your chain/agent’s needs. This will mitigate though not eliminate the risks of building a model-driven system. For more on general security best practices, see here.

In this example, we are querying a public dataset, and I followed best practice by configuring Trino’s Iceberg connector with a read-only application key scoped to the bucket containing the Drive Stats Iceberg tables.

Now let’s stream a new question through the flow. This mode of operation displays the output of each step as it is executed, essential for understanding the flow’s behavior, particularly when it is behaving unexpectedly. The model returns structured text in Markdown format. With a couple of lines of code to extract the message from the step variable, we can use the display_markdown function to render each step’s output:

for step in graph.stream(
    {"question": "Each drive has its own serial number. How many drives did each data center have on 9/1/2024"}, stream_mode="updates"
):
    # unwrap the step value to get the markdown message
    state = one(step.values())
    message = one(state.values())
    display_markdown(message, raw=True)

This is the model’s output, and it gives us three different messages. I’ve separated them with a horizontal line for clarity:

SELECT datacenter, COUNT(DISTINCT serial_number) AS drive_count FROM drivestats WHERE date = ‘2024-09-01’ GROUP BY datacenter ORDER BY drive_count DESC LIMIT 10


Error: (trino.exceptions.TrinoUserError) TrinoUserError(type=USER_ERROR, name=TYPE_MISMATCH, message=”line 3:12: Cannot apply operator: date = varchar(10)”, query_id=20250113_221649_00214_bsut5) [SQL: SELECT datacenter, COUNT(DISTINCT serial_number) AS drive_count FROM drivestats WHERE date = ‘2024-09-01’ GROUP BY datacenter ORDER BY drive_count DESC LIMIT 10] (Background on this error at: https://sqlalche.me/e/20/f405)


The SQL query encountered an error because it attempted to compare a date column with a string in the format ‘YYYY-MM-DD’. Specifically, the error message indicates that the date column is of a different type (likely not a string), which is causing the type mismatch.

To answer the user question about how many drives each data center had on 9/1/2024, the SQL query needs to be corrected. Here’s the revised query:

SELECT datacenter, COUNT(DISTINCT serial_number) AS drive_count 
FROM drivestats 
WHERE date = DATE '2024-09-01' 
GROUP BY datacenter 
ORDER BY drive_count DESC 
LIMIT 10

This corrected query uses the DATE keyword to ensure that the date string is properly interpreted as a date type, which should resolve the type mismatch error. If executed successfully, this query will provide the count of distinct drives in each data center for the specified date. However, without executing the corrected query against the database, we cannot provide the exact counts.

As you can see in the output from the first step, the model generated an invalid query, comparing a date to a string, despite the database schema being included in the prompt. The output of the second step contains the resulting error message from the database, while the third step contains the model’s diagnosis of the error.

This exchange highlights a limitation of a flow that is simply a linear series of steps, such as write_query, execute_query, and generate_answer. We cannot rely on the model to generate a valid SQL query, although it is able to point the way towards resolving its error.
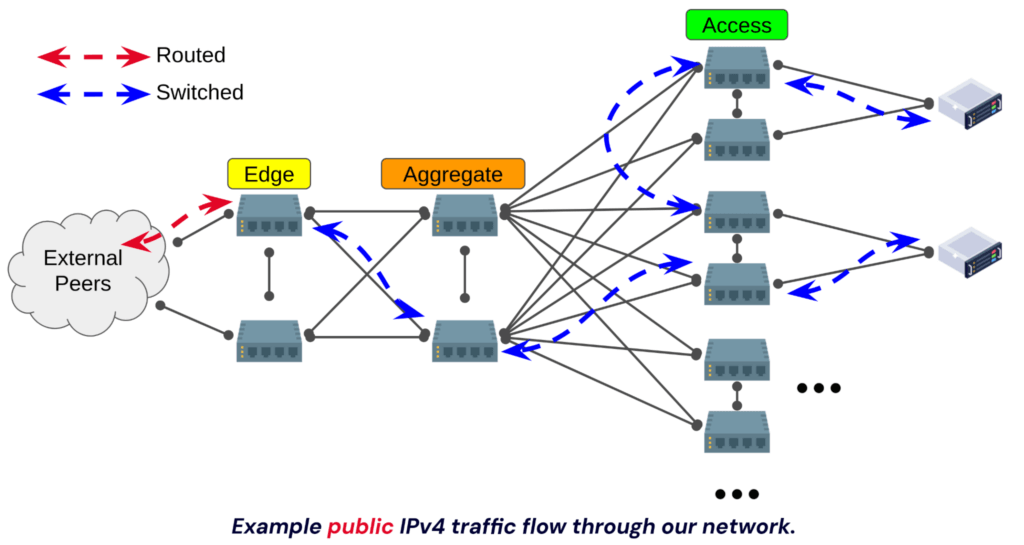
Creating a ReAct AI agent with LangGraph

The LangGraph framework gives you the capability to create AI agents based on arbitrarily complex logic. In this article, I’ve used its prebuilt ReAct (Reason+Act) agent, since it neatly demonstrates the agent concept, rewriting the SQL query repeatedly in response to database errors.

There are three steps to creating the agent. The first is to create an instance of LangChain’s SQLDatabaseToolkit, passing it the database and model, and obtain its list of tools:

toolkit = SQLDatabaseToolkit(db=db, llm=llm)
tools = toolkit.get_tools()

The tools list contains tools that execute queries, retrieve the names, schemas and content of database tables, and check SQL query syntax.

The next step is to retrieve a suitable prompt template from the Prompt Hub and populate the template placeholders:

prompt_template = hub.pull("langchain-ai/sql-agent-system-prompt")
system_message = prompt_template.format(dialect=db.dialect, top_k=10)

Here is the prompt template’s text:

================================ System Message ================================

You are an agent designed to interact with a SQL database.
Given an input question, create a syntactically correct {dialect} query to run, then look at the results of the query and return the answer.
Unless the user specifies a specific number of examples they wish to obtain, always limit your query to at most {top_k} results.
You can order the results by a relevant column to return the most interesting examples in the database.
Never query for all the columns from a specific table, only ask for the relevant columns given the question.
You have access to tools for interacting with the database.
Only use the below tools. Only use the information returned by the below tools to construct your final answer.
You MUST double check your query before executing it. If you get an error while executing a query, rewrite the query and try again.

DO NOT make any DML statements (INSERT, UPDATE, DELETE, DROP etc.) to the database.

To start you should ALWAYS look at the tables in the database to see what you can query.
Do NOT skip this step.
Then you should query the schema of the most relevant tables.

Now we can create an instance of the prebuilt agent:

agent_executor = create_react_agent(llm, tools, 
state_modifier=system_message)

Note how the agent must select the next step, and how the flow can cycle between the agent and tools steps:

display(Image(agent_executor.get_graph().draw_mermaid_png()))
A diagram showing the workflow between tools and agent. The workflow is as follows: start, agent, then a split option to access tools (a recursive step), or to end. The diagram shows that after agent, you can optionally select tools or end, indicating that you can end without choosing tools.
Again, we can stream the agent’s execution to show us each step of its operation.

for step in agent_executor.stream(
    {"messages": [{"role": "user", "content": "Each drive has its own serial number. How many drives did each data center have on 9/1/2024?"}]},
    stream_mode="values",
):
    step["messages"][-1].pretty_print()

The output from this flow is over 300 lines long; I posted it in its entirety as a Gist, but I’ll summarize the steps here:

  • Question: Each drive has its own serial number. How many drives did each data center have on 9/1/2024?
  • The model calls the “list tables” tool.
  • The list tables tool responds with a single table name, drivestats.
  • The model calls the “get schema” tool, passing it the table name.
  • The get schema tool responds with the schema and three sample rows from the drivestats table.
  • The model submits a query to the “query checker” tool:
    SELECT datacenter, COUNT(serial_number) AS drive_count FROM drivestats WHERE date = '2024-09-01' GROUP BY datacenter ORDER BY drive_count DESC LIMIT 10;
  • The query checker responds with the checked query, which is the same as its input. Note that the query checker only checks the SQL query’s syntax. The query contains the same data type mismatch as the query we generated earlier, as well as another error, as we’re about to discover.
  • The model submits the query to the “query executor” tool.
  • The query executor responds with a syntax error—Trino does not allow a trailing semi-colon on the query.
  • The model submits a modified query to the query checker tool:
    SELECT datacenter, COUNT(serial_number) AS drive_count FROM drivestats WHERE date = '2024-09-01' GROUP BY datacenter ORDER BY drive_count DESC LIMIT 10
  • The query checker responds with the checked query, which is the same as its input.
  • The model submits the query to the “query executor” tool.
  • The query executor responds with a type mismatch error since the query tries to compare a string value with a date column.
  • The model submits a query with the necessary DATE type identifier to the query checker tool:
    SELECT datacenter, COUNT(serial_number) AS drive_count FROM drivestats WHERE date = DATE '2024-09-01' GROUP BY datacenter ORDER BY drive_count DESC LIMIT 10
  • The query checker responds with the checked query, which is the same as its input.
  • The model submits the query to the “query executor” tool.
  • The query executor responds with a result set:
    [
      ('phx1', 89477),
      ('sac0', 78444),
      ('sac2', 60775),
      ('', 24080),
      ('iad1', 22800),
      ('ams5', 16139)
    ]
  • The model returns a message containing the answer:

On September 1, 2024, the following datacenters had the specified number of drives:

1. phx1: 89,477 drives
2. sac0: 78,444 drives
3. sac2: 60,775 drives
4. (unknown datacenter): 24,080 drives
5. iad1: 22,800 drives
6. ams5: 16,139 drives

These results show the datacenters with their respective drive counts.

Now let’s see if the model can calculate the annualized failure rate of a drive model. We’ll use the Seagate ST4000DM000, just because that is the drive model with the most days of operation in the dataset.

for step in agent_executor.stream(
        {"messages": [{"role": "user", "content": "Each drive has its own serial number. What is the annualized failure rate of the ST4000DM000 drive model?"}]},
        stream_mode="values",
):
    step["messages"][-1].pretty_print()

The agent’s response mixes Markdown and LaTex notation. I used QuickLaTeX to render the LaTex to images:

The annualized failure rate (AFR) for the ST4000DM000 drive model can be calculated using the following information:

– Total failures: 5,791

– Total drives: 37,040

– Time period: from May 10, 2013, to September 30, 2024, which is approximately 11.35 years.

The formula for calculating the annualized failure rate is:

The calculation for the annualized failure rate. It's total failures divided by total drives, multiplied by one over the total years, multiplied by 100.

Plugging in the numbers:

Real number for the annualize failure rate calculations. In this instance, the text reads 5791 divided by 37040, multiplied by one over 11.35, multiplied by 100, which equals approximately 13.77 percent.

Therefore, the annualized failure rate (AFR) of the ST4000DM000 drive model is approximately 13.77%.

It’s impressive that the agent shows its working so comprehensively, but, unfortunately, it arrives at the wrong answer. Those drives were not all running for the entire span of the Drive Stats dataset. The correct calculation involves determining the number of days with data for those drives and dividing it by 365 to get the correct number of years’ operation.

It’s clear that the model is not able to answer questions on drive reliability given the data available to it so far. The solution lies in prompt engineering—providing more context on the semantics of the data in the system prompt.

We can extend the default AI agent system prompt template to include specific instructions on working with the Drive Stats dataset:

prompt_template.messages[0].prompt.template += """
Each row of the drivestats table records one day of a drive’s operation, and contains the serial number of a drive, its model name, capacity in bytes, whether it failed on that day, SMART attributes and identifiers for the slot, pod, vault, cluster and data center in which it is located.

Use this calculation for the annualized failure rate (AFR) for a drive model over a given time period:

1. **drive_days** is the number of rows for that model during the time period.
2. **failures** is the number of rows for that model during the time period where **failure** is equal to 1.
3. **annual failure rate** is 100 * (**failures** / (**drive_days** / 365)).

Use double precision arithmetic in the calculation to avoid truncation errors. To convert an integer **i** to a double, use CAST(**i** AS DOUBLE)

Note that the date column is a DATE type, not a string. Use the DATE type identifier when comparing the date column to a string.

Do not add a semi-colon suffix to SQL queries."""

Now, when we ask the same question on the annual failure rate of the ST4000DM000 drive model, the AI agent generates a correct SQL query and a more concise, and correct, final response (you can inspect the full output here).

SELECT 100 * (CAST(COUNT(CASE WHEN failure = 1 THEN 1 END) AS DOUBLE) / (COUNT(*) / 365)) AS annual_failure_rate
FROM drivestats
WHERE model = 'ST4000DM000'

The annual failure rate (AFR) for the ST4000DM000 drive model is approximately 2.63%.

Let’s ask the AI agent for a statistic that we can corroborate from the Backblaze Drive Stats for Q3 2024 blog post.

response = agent_executor.invoke(
    {"messages": [{"role": "user", "content": "What was the annual failure rate of the ST8000NM000A drive model in Q3 2024?"}]}
)
response['messages'][-3].pretty_print()
display_markdown(response['messages'][-1].content, raw=True)

The query makes sense, and the response agrees with the table in the blog post:

SELECT 100 * (CAST(SUM(failure) AS DOUBLE) / (COUNT(*) / 365)) AS annual_failure_rate
FROM drivestats
WHERE model = 'ST8000NM000A' AND date >= DATE '2024-07-01' AND date < DATE '2024-10-01'

The annual failure rate (AFR) of the ST8000NM000A drive model in Q3 2024 is approximately 1.61%.

Interestingly, this time the SQL query used SUM(failure) to count the number of failures, rather than the equivalent, but rather long-winded COUNT(CASE WHEN failure = 1 THEN 1 END) it used in the previous query. Also, looking at the full response, we can see that, as directed by the custom prompt, the agent generated the correct syntax for comparing dates, so it didn’t need to correct and retry any queries.

Finally, let’s ask a more convoluted question, including the constraints given in the blog post:

response = agent_executor.invoke(
    {"messages": [{"role": "user", "content": "Considering only drive models which had at least 100 drives in service at the end of the quarter and which accumulated 10,000 or more drive days during the quarter, which drive had the most failures in Q3 2024, and what was its failure rate?"}]}
)
response['messages'][-3].pretty_print()
display_markdown(response['messages'][-1].content, raw=True)

Again, the AI agent is able to generate a valid SQL query, this time including a subquery, and its response matches the data from the blog post exactly:

WITH drive_stats AS (
    SELECT model,
           COUNT(DISTINCT serial_number) AS drive_count,
           COUNT(*) AS drive_days,
           COUNT(CASE WHEN failure = 1 THEN 1 END) AS failures
    FROM drivestats
    WHERE date >= DATE '2024-07-01' AND date < DATE '2024-10-01'
    GROUP BY model
    HAVING COUNT(DISTINCT serial_number) >= 100 AND COUNT(*) >= 10000
)
SELECT model,
       failures,
       100 * (CAST(failures AS DOUBLE) / (CAST(drive_days AS DOUBLE) / 365)) AS failure_rate
FROM drive_stats
ORDER BY failures DESC
LIMIT 10

The drive model with the most failures in Q3 2024 is the TOSHIBA MG08ACA16TA, which had 181 failures. Its failure rate during this period was approximately 1.84%.

Closing thoughts

My experience building an AI agent was astonishment at its ability to correctly generate quite complex SQL queries based on natural language instructions, tempered with frustration at its limitations, particularly the way that it would confidently generate an incorrect response, rather than saying “I’m sorry, but I don’t know how to do that.” Your AI agent development process should include generous testing time, as well as ongoing monitoring to ensure that it is coming up with the right answers.

The post Building an AI Agent with Backblaze B2, LangChain, and Drive Stats appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

AI 101: Building and Deploying an AI Model

Post Syndicated from Stephanie Doyle original https://www.backblaze.com/blog/ai-101-building-and-deploying-an-ai-model/

A decorative image showing a computer, a cloud, and a building.

Should you build your own AI model? Or use other services to help you accelerate the process?

Once you’ve defined the problem you’re trying to solve and the AI model type that best fits your needs, these are the questions you’re faced with next—where to deploy an AI model and how to go about doing it. In most cases, there is very little reason for you to build, train, and deploy your AI model from scratch, particularly as more and more vendors are stepping in to help companies with all or some of the process. It’s fundamentally complex, takes tons of resources and requires specialized knowledge to do correctly. 

Still, you should have a basic understanding of the AI model training and deployment processes, as these learnings will be useful as later on as you explore various predefined tools, applications, and services you can use to expedite or enhance your ability to use AI within your organization. That’s what I’m digging into today.

How AI model training works

There are several steps in training an AI model which include identification and gathering the data required, data cleansing and assembly, training the model, checkpointing, and, finally, model serving where the model is deployed into the production environment. Here’s an overview of the process. 

A diagram that explains the AI model training process.

Let’s take a minute to explore each of the steps in a little more detail.

Step 1: Review 

The organizational data needed to help educate your model will either be structured or unstructured. Structured data is found in databases, tables, and so on. Unstructured data is basically everything else. Some unstructured data is easy to process, such as text files, while other data is harder to extract, such as PDFs and images. 

In general, the more data you can provide, the better your trained model can be. But, remember to include data that is not what you want as well—this helps models to hone in on the specific piece of information when things are similar. Take this example scenario, for instance:  

You are monitoring hundreds of thousands of wooded acres to determine if there is a fire on the land. As part of training the model, you need to provide images of the legitimate flora and fauna along with images of fire. But you should also provide images of what is not fire, for example reflections of the sun or moon on a lake, a group of lightning bugs at night, car headlights, and so on.

Step 2: Clean 

As the data is collected, it will need to be pre-processed, which involves several techniques such as cleaning the data to handle missing values, removing outliers, scaling features, encoding categorical variables, and splitting the data into training and testing sets. The data needs to be arranged in a manner acceptable to the model itself. This sounds relatively simple, but some studies show that this can take up to 80% of the total model development process time

Step 3: Stage 

This is a collection point for all of the clean, ready to be processed, data. This data will arrive as it is processed (cleaned) which can occur over several days or even weeks. Having this data on hand will be useful if the model is not generated correctly or in the future as a starting point to retrain the model.

Typically large amounts of your data will be cleaned and staged as it is readied to train the AI model. But, there are no special storage requirements for this data. It just needs to be readily available to be uploaded to the AI training environment when the time comes. 

Step 4: Train 

Model training is a resource intensive process where data is copied from staging to high-performance storage located in close proximity to whatever high-powered processor you’re rocking, usually a graphical processing unit (GPU). The GPUs then run the algorithms developed specifically for training the model, and the data is iteratively read and processed an indeterminate number of times until training is complete. Minimizing the time spent utilizing these expensive, high-powered storage and processing resources is critical in managing the overall cost of building the model. In other words: get in, process, and get out.

Step 5: Checkpoint 

During the building of the model, the programming will often create snapshots of the status of the training process. This will include various variables, state changes, and so on. These snapshots are referred to as checkpoints. They initially will be written to local storage within the model training system, and are used to restart the training process from a known good state if something goes wrong. 

Once the model training process is complete, checkpoints should be written to the same centralized data storage location as your staged data. The checkpoint data will become part of the documentation of the model and may be used for forensic purposes should the model not behave appropriately once it is deployed.

Step 6: Serve 

Once the training process is complete, the model can be exported to your central storage location. This will once again help document the system, and from there the model can then be uploaded to the local or cloud compute environment where it will be used.  

At this point you have a clean version of the source data, the checkpoints of the model created, and a copy of the model itself, all stored in your centralized location under your control and readily available should they be needed in the future. 

AI model inference

The term inference is derived from the AI model’s perspective. At a high level, when given a prompt, the model infers its response from the trained model and its data. In simple terms, you’ve trained your model to recognize cats, and then you bring it new data (a picture of a family reunion) and ask your model if it sees any cats in the photo (I’m hoping the answer is yes). 

In AI, the prompt is viewed as new data which is compared to the model’s existing data to determine a response typically in the form of a decision, prediction, or new content as is the case with generative AI models. 

An overview of the inference process is below:

A diagram of the AI inference process.

In some AI systems, the inference process flow includes some additional code to help improve your model. These types of filters can have a range of uses and can happen on either the input or the output stage. For example, if you want to filter inappropriate queries or information, you could include something like keyword filtering when data (the prompt) is input. Or, you could introduce a toxicity detection filter on the output side, which reviews responses and prevents harmful or offensive content to be presented to the user.  

A perhaps better understood problem that filters like this can address is how to get accurate and up-to-date information out of your queried response. On the input flow side of things, retrieval-augmented generation (RAG) directs a trained model to incorporate and weight more heavily information from trusted sources that the user designates. On the output side, you might add a hallucination prevention filter, which would stop the model from presenting false or misleading information.  

More broadly, you’ll notice that both the prompt and response are saved. It is important to review this information on a periodic basis. This is especially true if the model is public facing, if  you are using a model which can change over time such as a foundation model, or if you are using a model which utilizes RAG techniques to include new or external content. 

In all of those examples, your model can drift as new information is introduced, and, as we noted above, getting the right information and cleaning it properly is likely the most time-intensive and important stage of this process. Not for nothing is the phrase “knowledge is power” a truism—in the age of AI, knowledge is power and good data is king. 

The post AI 101: Building and Deploying an AI Model appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Solving the AI Training Data Challenge with Decart AI and Backblaze

Post Syndicated from Stephanie Doyle original https://www.backblaze.com/blog/solving-the-ai-training-data-challenge-with-decart-ai-and-backblaze/

A decorative image showing the logos of Backblaze and Decart.

Depending on which LLM you ask, we live in a world with somewhere between 25k and 80k AI startups. It’s a growing, highly competitive market where small startups with a big idea can find themselves toe-to-toe with the goliaths of tech—fighting for money, chips, talent, even raw electrical power. 

How does any company differentiate themselves in an explosive burst of technological change, one that requires a lot of investment in talent and infrastructure, where even the richest tech platforms on the planet don’t always succeed? Today we’re sharing the story of Decart—an AI startup that used Backblaze B2 Cloud Storage to leverage a successful launch with an impressive new model that provides an order of magnitude improvement in both the training and inferencing of the largest generative models.

Backblaze is an amazing solution for AI training data. We looked at a number of options and  Backblaze is seriously the best.

—Dean Leitersdorf, Co-Founder and CEO, Decart

First, the news

Decart is an AI research lab that came out of stealth on October 31 with an incredible new model:

While this might look like Minecraft, every pixel you see here and all of the gameplay is being generated by Decart’s Oasis model. It’s like Minecraft in every way you’d expect, except that the entire experience is being generated by AI and you can creatively prompt the model to build beyond the confines of the game. The mindblowing part? Decart says Oasis can perform more than 10 times more efficiently than competitors such as OpenAI’s Sora, which hasn’t been publicly released.

Don’t let the game distract you though—the Minecraft simulation is just an expression of the power of their model. According to the Decart team, this isn’t even version 1.0 of what their approach is capable of generating—more like version 0.01. Given the broad coverage they’ve already received for their launch, we’re excited to see what’s next.

How to break out in the AI market

For Decart, the strategy to pull ahead of the crowd was simple: Disrupt the market on inference speed to deliver game changing models, and do that by building the most high-performance multi-cloud model training infrastructure possible. Then, iterate on that innovation. 

We crafted state of the art infrastructure that allows us to train models that other people simply can’t train.

—Dean Leitersdorf, Co-Founder and CEO, Decart

Before we met Dean and the team at Decart, most of the hard work was done: the multi-cloud AI stack for training was dialed in and the models were going through the paces. They just had one simple, but big, problem holding them back:

The price and the logistics of moving and storing training data were going to limit their growth.

They were burning through free data storage credits from a traditional cloud provider and had data spread across a range of other cloud providers and GPU clusters. Their training data needed to scale from 100s of thousands of hours of video data to 100s of millions of hours, and they needed a storage solution that could handle that scale in three key areas:

  1. Reliably high performance: Decart needed to know that when they got time on a cluster, they could move data in as fast as possible the second that they were able to. 
  2. GPU interoperability: They needed to be sure that whatever storage platform they chose, it would work well with a multi-cluster training approach. Being able to shop jobs between different GPU clouds and disperse training was essential for Dean’s team.
  3. Efficiency: Every dollar an AI startup spends on anything other than training time is a competitive disadvantage, so ensuring that storage costs were low without any surprise fees for data retention or download was key.

Decart discovered Backblaze while researching storage alternatives. After a quick call and two fast months of testing Backblaze in a wide variety of usage patterns, it was clear to the team that they had found the storage foundation they needed. 

We chose Backblaze because everything works. It’s super stable, and we had zero problems.  That’s number one.

—Dean Leitersdorf, Co-Founder and CEO, Decart

When it came time to start moving data from Backblaze to GPU clusters, they had no problem with transferring petabyte-scale datasets. The only minor challenge was ensuring that the compute provider’s pipe could take the volume of data streaming in.

Here’s where things ended up working for Decart:

  • Performance: They were blown away by the performance they achieved with Backblaze (more to come on that later).
  • Price: With pricing at one-fifth the cost of traditional cloud providers, Backblaze unlocked a significant amount of budget.
  • Free egress: The true game changer. Decart, for a number of reasons, trains their models on multiple different GPU clusters at the same time. With Backblaze, they can egress their full dataset to up to three training sites with zero additional cost.

B2 Cloud Storage was literally the only technical thing we used in training these models that didn’t crash the first time we tried it. We’re in an industry where everything fails, but Backblaze didn’t.

—Dean Leitersdorf, Co-Founder and CEO, Decart

Looking forward

With performance, flexibility, and affordability squared away in their data storage approach, the Decart team is now in position to rotate out of this impressive first model and build whatever is next. With all the fundamentals working on the level that Backblaze always provides and Decart is happy with, the two teams are now working together to find even more efficiency and optimization and truly stand up the best infrastructure for training AI models.

The post Solving the AI Training Data Challenge with Decart AI and Backblaze appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Announcing Support for IPv6

Post Syndicated from Anthony Hoppe original https://www.backblaze.com/blog/announcing-support-for-ipv6/

An illustration of network connections on a gradient background.

If your systems are IPv6-enabled or enabling IPv6 is on your roadmap, good news—starting yesterday and continuing over the course of the next few weeks, Backblaze will be “flipping the switch” and turning on IPv6 for our S3 Compatible API. While our IPv6 deployment isn’t completely done yet (we’re phasing the roll out through our environment), we thought we’d share some of the decisions we made that affect performance and functionality.   

Today, I’ll talk a little bit more about our choices along the way, and answer some questions that might come up about how we’re supporting the protocol (jump to the FAQ for that).

Hi, I’m Anthony

Since this is the first time you’re hearing from me, I thought I should introduce myself. I’m a senior network engineer here at Backblaze. The Network Engineering group is responsible for ensuring the reliability, capacity, and security of network traffic, and that includes our IPv6 deployment.

What is IPv6 and why did we enable it?

Internet protocol version 6 (IPv6) is replacing internet protocol version 4 (IPv4) as the standard for IP addresses. Most of the internet uses IPv4, and this protocol has been reliable and resilient for over 20 years. However, IPv4 has limitations that might cause problems as the internet expands—namely, there aren’t enough IPv4 addresses to go around

Demand for IPv6 is continuing to increase exponentially. A major factor in this is the combination of the continually growing population and the number of connected devices a given person carries. One study from 2020 suggests the average number of connected devices per person globally was 2.4 in 2018, and forecasted to be 3.6 in 2023. Specifically for North America, the study suggests 8.2 connected devices in 2018 and a whopping 13.4 in 2023! Every device connected to the internet needs an IP address, and the finite address space of IPv4 it is simply no longer sufficient. The key to IPv6 enhancement is the expansion of the IP address space from 32 bits to 128 bits, enabling virtually unlimited, unique IP addresses.

Support for IPv6 means our customers can reach our services in the most efficient and secure way possible.

Why should you care about us deploying IPv6?

We’ve learned some things over the years, so we approached our IPv6 deployment a little differently than our IPv4 deployment. If you’re a customer or potential customer, here’s what that means for you: 

  1. No action needed on your part: Unlike some of the traditional cloud providers, we chose to use the same endpoint URL and let the client choose whether or not to use IPv6. This allows for any systems already IPv6 enabled to benefit immediately. In fact, if your systems are IPv6 enabled and you are a B2 customer using the S3 compatible API, you might already be connecting to us over IPv6 now.
  2. Our deployment is better set up to scale: Because of the way we decided to assign virtual IPs (VIPs) to our API endpoints, we have more flexibility to distribute ingress traffic and the ability to add VIPs as we need to in the future.
  3. Improved network performance and simpler network management: With IPv6, we simplified IP assignments and reduced the need for customers to use Network Address Translation (NAT). NAT adds processing overhead to network traffic as it translates IP addresses, which can lead to latency issues, especially with high-volume data transfer. The less traffic you have to NAT, the better. On our end, there is no NAT with customer data flows regardless of IPv4 vs IPv6. We also made the decision to route traffic before using network switches, this helps with reducing IPv6 multicast “noise” and generally helps keep the “wire” cleaner.

And here’s how we got it all done.

If a VIP could only talk

First, a little background: Backblaze offers two APIs—the Backblaze S3 Compatible API and the Backblaze B2 Native API. You can learn more about our APIs here in our documentation, but a couple differences are important to note when it comes to our IPv6 deployment:

  • Backblaze B2 Native API: Uploads are sent directly to a Backblaze Vault. As part of the process of uploading a file, the client is provided an “upload URL”, which is a direct URL to an assigned member of the storage Vault. The data transfer is direct from the client to the storage Vault. Only downloads are served by the API server pool. Load balancers mainly handle distributing API calls.
  • S3 Compatible API: Uploads flow through load balancers and the API server pool. Our API server pool then distributes the data to the assigned Vault. Downloads are served by our API server pool just like Backblaze B2 Native API.

These functionality differences play a role in how we are able to perform traffic engineering.  We assign VIPs to our API endpoints, for example, s3.us-west-004.backblazeb2.com, or api004.backblazeb2.com. These VIPs are owned by our load balancers and API servers (for Direct Server Return). With the Backblaze B2 Native API, we really only need two VIPs per cluster: one for uploads and one for downloads. The upload URL that B2 Native provides to the client naturally distributes the flow across our IP space. With the S3 Compatible API, since uploads and downloads are handled by the same flow, we only needed one VIP…or so we thought.

Assigning a single VIP to the S3 Compatible API has been fine for a long time. However, as we’ve grown, and usage of the S3 Compatible API has grown, we discovered that a single S3 Compatible API VIP makes traffic engineering ingress flows challenging. When a large percentage of our S3 Compatible API ingress traffic happens to come from providers that prefer getting to us via a single path, having all that traffic destined to a single IP means we have no ability to steer (i.e.traffic engineer) portions of the traffic.

Starting at the beginning of this year, we’ve grown the number of API VIPs in our datacenters with the highest amount of S3 Compatible API traffic from a single IP, to four IPs in four different network prefixes (also known as subnets). This allows us to steer portions of S3 Compatible API traffic. This also helps distribute flows so that providers that have equal cost paths to us can be better utilized.

Lesson learned: With IPv6, we standardized on four IPv6 VIPs in four different prefixes with plans to grow if/when needed.

Route when you can, switch only when you need to

Backblaze datacenter networks are architected using a typical “three tier” approach. We have an edge layer, an aggregation layer (also known as a spine), and an access layer (also known as a leaf).

A diagram of a three-tier network design.

With IPv4, we have two IP “classes”. We have a private network (RFC 1918) and a public network. Every machine is assigned an IPv4 address on the private network, and only machines that need to directly interface with the outside world are assigned public IPv4 addresses. These two networks each reside within their own VLAN, and host networking is configured to tag traffic as necessary.

Given the tiered design of our network, different layers handle these VLANs. The aggregation layer acts as the router for the private network, and the edge layer acts as the router for the public network. From there, IPv4 traffic is switched, and thus we simply have two large (i.e. flat) VLANs for IPv4.

A diagram showing an example of how private IPv6 traffic travels through a network.
A diagram showing an example of how public IPv6 traffic travels through a network.

This has worked well (and still works just fine). A pair of VLANs that we can switch to anywhere in the datacenter keeps things simple. Hosts can reside anywhere within the datacenter and IPs can be assigned from the same pools. However, with IPv4 traffic being switched datacenter wide, the flat broadcast domain (thus the level of background broadcast noise) increases over time as the environment grows. In our largest (IP-space wise) datacenter we’ve needed to increase hosts’ arp cache size. With IPv6, we wanted to improve this.

The first decision we made was to eliminate the concept of public vs private address space with IPv6. Every host gets an address and all addresses are public (if the role requires). Existing firewalls and switch ACLs already permit/deny traffic as appropriate (which is also the same for our IPv4 networks).

Not only does this simplify IP assignments, it also reduces the need for Network Address Translation (NAT). We have many hosts that are not public facing, but do need to communicate with the outside world for various reasons. As we are able to move more and more communication with external services to IPv6, this reduces the load on resources we’ve deployed simply to handle NAT.

The second decision that we made was to route all the way down to the access switch layer.  Each access switch is assigned a /64 and hosts connected to a given switch are assigned an IPv6 address from a portion of this block.

A diagram showing an example of how IPv6 traffic travels through the Backblaze network.

This helps with reducing IPv6 multicast “noise” and generally helps keep the “wire” cleaner.  It does make host deployments a little more complicated as in order to assign a given host an IPv6 address from the correct network, one needs to be aware of the switch the host is connected to. Also, if data center staff need to move hosts around for power balancing or consolidation, the IPv6 address will need to be changed if the new location results in the host connecting to a different switch. 

Lesson learned: Even with the added complexity, the route when you can, switch only when you need to mantra works well for our environment.

What’s next?

We still have more work ahead. We are currently investigating ways to support the Backblaze B2 Native API with IPv6 as well as Backblaze Computer Backup. Stay tuned for more on that front.

FAQs

What’s the difference between IPv4 and IPv6?

The key difference between the versions of the protocol is that IPv6 has significantly more address space. The IPv6 address notation is eight groups of four hexadecimal digits with the groups separated by colons, for example 2001:db8:1f70:999:de8:7648:3a49:6e8, although there are methods to abbreviate this notation. For comparison, the IPv4 notation is four groups of decimal digits with the groups separated by dots, for example 198.51.100.1.

The expanded addressing capacity of IPv6 will enable the trillions of new internet addresses needed to support connectivity for a huge range of new devices such as phones, household appliances, and vehicles.

How can I use IPv6 with B2 Cloud Storage?

Currently, only the Backblaze S3-compatible API supports IPv6. To use IPv6 addresses with B2 Cloud Storage and the S3-compatible API, you do not need to make any changes.

Will IPv4 addresses still work?

Yes, IPv4 addresses will continue to be supported for both the B2 Native API and the S3-compatible API for the time being. We do not have any explicit plans for sunsetting IPv4 at this time.

What will happen if I continue to use IPv4?

Nothing. IPv4 will continue to be supported at this time.

Is IPv6 better/more secure than IPv4?

It is not more secure. Customers who reach us via IPv4 or IPv6 will have connections that are equally secure. Our APIs use the same strong TLS encryption regardless if IPv4 or IPv6 is used. Some customers may see a performance improvement if IPv6 allows them to avoid network address translation (NAT).

Is there an additional cost to use IPv6?

No.

I’m using Backblaze Computer Backup. Do I need to make any changes?

No. IPv6 is only relevant for Backblaze B2 Cloud Storage. You don’t need to make any changes to your Backblaze Computer Backup account.

The post Announcing Support for IPv6 appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

How to Zip Files with the Python S3fs Library + Backblaze B2 Cloud Storage

Post Syndicated from Pat Patterson original https://www.backblaze.com/blog/how-to-zip-files-with-the-python-s3fs-library-backblaze-b2-cloud-storage/

A decorative image showing the Backblaze logo on a cloud over a pattern representing a network.

Whenever you want to send more than two or three files to someone, chances are you’ll zip the files to do so. The .zip file format, originally created by computer programmer Phil Katz in 1986, has become ubiquitous; indeed, the dictionary definition of the word zip includes this usage of zip as a verb.

If your web application allows end users to download files, it’s natural that you’d want to provide the ability to select multiple files and download them as a single .zip file. Aside from the fact that downloading a single file is straightforward and familiar, the files are compressed, saving download time and bandwidth.

There are a few ways you can provide this functionality in your application, and some are more efficient than others. Today, inspired by a question from a Backblaze customer, I’m talking through a web application I created that allows you to implement .zip downloads in your application with data stored in Backblaze B2 Cloud Storage. 

First: Avoid this mistake

When writing a web application that stores files in a cloud object store such as Backblaze B2 Cloud Storage, a simple approach to implementing .zip downloads would be to:

  1. Download the selected files from cloud object storage to temporary local storage.
  2. Compress them into a .zip file.
  3. Delete the local source files.
  4. Upload the .zip file to cloud object storage.
  5. Delete the local .zip file.
  6. Supply the user with a link to download the .zip file.
A diagram showing how to download zip files from Backblaze B2 to local storage

There’s a problem here, though—there has to be enough temporary local storage available to hold the selected files and the resulting .zip file. Not only that, but you have to account for the fact that multiple users may be downloading files concurrently. Finally, no matter how much local storage you provision, you also have to handle the possibility that a spike in usage might consume all the available local storage, at best making downloads temporarily unavailable, at worst destabilizing your whole web application.

Troubleshooting a better way

If you’re familiar with piping data through applications on the command line, the solution might already have occurred to you: Rather than downloading the selected files, compressing them, then uploading the .zip file, stream the selected files directly from the cloud object store, piping them through the compression algorithm, and stream the compressed data back to a new file in the cloud object store.

A diagram showing how to create ZIP files from Backblaze B2 by streaming them to a compression engine.

The web application I created allows you to do just that. I learned a lot in the process, and I was surprised by just how compact the solution was, just a couple dozen lines of code, once I’d picked the appropriate tools for the job.

I was familiar with Python’s zipfile module, so it was a logical place to start. The zipfile module provides tools for compressing and decompressing data, and follows the Python convention in working with file-like objects. A file-like object provides standard methods, such as read() and/or write(), even though it doesn’t necessarily represent an actual file stored on a local drive. Python’s file-like objects make it straightforward to assemble pipelines that read from a source, operate on the data, and write to a destination—exactly the problem at hand.

My next thought was to reach for the AWS SDK for Python, also known as Boto3. Here’s what I had in mind:

b2_client = boto3.client('s3')

# BytesIO is a binary stream using an in-memory bytes buffer
with BytesIO() as buffer:
# Open a ZipFile object for writing to the buffer
with ZipFile(buffer, 'w') as zipfile:
for filename in selected_filenames:
# ZipInfo represents a file within the ZIP
zipinfo = ZipInfo(filename)
# You need to set the compress_type on each ZipInfo
# object - it is not inherited from the ZipFile!
zipinfo.compress_type = ZIP_DEFLATED
# Open the ZipInfo object for output
with (zipfile.open(zipinfo, 'w') as dst):
# Get the selected file from B2
response = b2_client.get_object(
Bucket=input_bucket_name,
Key=filename,
)
# Copy the file data to the archive member
copyfileobj(response['Body'], dst, COPY_BUFFER_SIZE)

# Rewind to the start of the buffer
buffer.seek(0)
# Upload the buffer to B2
b2_client.put_object(
Body=buffer,
Bucket=output_bucket_name,
Key=zip_filename,
)

While the above code appears to work just fine, there are two issues. First, the maximum size of a file uploaded with a single put_object call is 5GB, and, second, the BytesIO object, buffer, holds the entire .zip file in memory. It may well be that your users will never select enough files to produce a .zip file greater than 5GB, but there is still a similar problem to the approach we started with: There needs to be enough memory available to hold all of the .zip files being concurrently created by users. We’re no further forward; in fact we’ve gone backwards–we traded a limited, but relatively cheap resource, disk space, for a more limited, more expensive resource: RAM!

It’s straightforward to upload files greater than 5GB using multipart uploads, splitting the file into multiple parts between 5MB and 5GB. I could rewrite my code to split the compressed data into chunks of 5MB, but that would add significant complexity to what seemed like it should be a simple task. I decided to try a different approach.

S3Fs is a “Pythonic” file interface to S3-compatible cloud object stores, such as Backblaze B2, that builds on Filesystem Spec (fsspec), a project to provide a unified Pythonic interface to all sorts of file systems, and aiobotocore, an asynchronous client for AWS. As well as handling details such as multipart uploads, allowing you to to write much more concise code, S3Fs allows you to write data to a file-like object, like this:

# S3FileSystem reads its configuration from the usual config files,
# environment variables. Alternatively, you can pass configuration
# to the constructor.
b2fs = S3FileSystem()

# Create and write to a file in cloud object storage exactly as you
# would a local file.
with b2fs.open(output_path, 'wb') as f:
for element in some_collection:
data = some_serialization_function(element)
f.write(data)

Using S3Fs, my solution for arbitrarily large .zip files was about the same number of lines of code as my previous attempt. In fact, I realized that the app should get each selected file’s last modified time to set the timestamps in the .zip file correctly, so this version actually does more:

zip_file_path = f'{output_bucket_name}/{zip_filename}'

# Open the ZIP file for output, open a ZipFile object
# for writing to the ZIP file
with b2fs.open(zip_file_path, 'wb') as f, ZipFile(f, 'w') as zipfile:
for filename in selected_filenames:
input_path = f'{input_bucket_name}/{filename}'

# Get file info, so we have a timestamp and
# file size for the ZIP entry
file_info = b2fs.info(input_path)

last_modified = file_info['LastModified']
date_time = (last_modified.year, last_modified.month, last_modified.day,
last_modified.hour, last_modified.minute, last_modified.second)

# ZipInfo represents a file within the ZIP
zipinfo = ZipInfo(filename=filename, date_time=date_time)
# You need to set the compress_type on each ZipInfo
# object - it is not inherited from the ZipFile!
zipinfo.compress_type = ZIP_DEFLATED
# Since we know the file size, set it in the ZipInfo
# object so that large files work correctly
zipinfo.file_size = input_file_info['size']

# Open the selected file for input,
# open the ZipInfo object for output
with (b2fs.open(input_path, 'rb') as src,
zipfile.open(zipinfo, 'w') as dst):
# Copy the data across
copyfileobj(src, dst, COPY_BUFFER_SIZE)

You might be wondering, how much memory does this actually use? The copyfileobj() call, right at the very end, reads data from the selected files and writes it to the .zip file. copyfileobj() takes an optional length argument that specifies the buffer size for the copy, so you can control the tradeoff between speed and memory use. I set the default in the b2-zip-files app to 1MiB.

This solves the problems we initially ran into, allowing you to offer .zip downloads without maxing out disk storage or RAM. 

My last piece of advice… Other than an easy .zip file downloader, I took one big lesson away from this experiment: Look beyond the AWS SDKs next time you write an application that accesses cloud object storage. You may just find that you can save yourself a lot of time!

The post How to Zip Files with the Python S3fs Library + Backblaze B2 Cloud Storage appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Do More with Backblaze B2: A Tour of the Backblaze GitHub Repositories

Post Syndicated from Pat Patterson original https://www.backblaze.com/blog/do-more-with-backblaze-b2-a-tour-of-the-backblaze-github-repositories/

A decorative image showing a computer with the GitHub logo and the Backblaze logo superimposed on files.

If you work with Backblaze B2, you’re probably already aware of resources such as the Backblaze B2 Python SDK and the Backblaze B2 Command Line Tool, but did you know that there is also a Terraform Provider for Backblaze B2, an SDK for Java, and a whole slew of open source samples showing how to integrate with Backblaze B2 from web browsers, serverless platforms, and more? Today, I’ll take you on a quick tour of our open source SDKs, tools, and sample code, pointing out some interesting sights along the way.

Why open source?

We’ve long been believers in open source code here at Backblaze, open sourcing our implementation of Reed-Solomon erasure coding back in 2015, and, even before then, sharing our Storage Pod designs and, of course, Drive Stats, the statistics and insights based on our observations of the hard drives we operate in our data centers, including the raw metrics we collect from many thousands of hard drives, every day.

While the Storage Pod designs and Drive Stats live here on the Backblaze website, we make our open source code available via two GitHub organizations:

Let’s take a closer look.

Official Backblaze SDKs and tools

You can use any of AWS’ range of SDKs, plus the AWS Command Line Interface (CLI), to access Backblaze B2 via its S3 Compatible API; just remember to configure the endpoint URL as well as the access key ID and secret access key.

Not every Backblaze B2 operation is accessible via the S3 Compatible API—for example, application key management—so we also support a range of open source SDKs for accessing Backblaze B2’s Native API from a variety of programming languages:

  • The Backblaze B2 Python SDK: This SDK provides access to the basic operations of the Native API, such as list_buckets() and download_file_by_id(), as well as a powerful Synchronizer class that implements high performance, multi-threaded file copying between Backblaze B2 and local file storage.
  • The Backblaze B2 Java SDK: Although it doesn’t include anything quite as sophisticated as the Python Synchronizer, the Java SDK does implement high-level functionality such as uploadLargeFile(), which encapsulates all of the mechanics of a multi-threaded file upload in a single method call. We also use it internally at Backblaze in our production environment. 
  • blazer, an open source Backblaze B2 SDK for Go (aka golang): We adopted blazer from its original author, Toby Burress, when he was no longer able to maintain it. We’ve made a few improvements since taking it on, and we’re looking at doing more with it.

The Backblaze GitHub organization also contains a pair of tools built on the Python SDK:

The remaining repositories contain utilities and other code that we have published over the years, including our open source Reed-Solomon erasure coding implementation and a utility we wrote to support migrating a live Cassandra cluster from one data center to another.

Backblaze sample and demo code

Our https://github.com/backblaze-b2-samples organization contains, at the time of writing, 34 repositories, demonstrating how to use Backblaze B2 in a wide variety of situations. We’ve covered a few of them in past blog posts:

As you explore the https://github.com/backblaze-b2-samples organization, you’ll also find repositories that have not yet been covered here on the Backblaze blog:

  • B2listen allows you to forward Backblaze B2 Event Notifications to a service listening on a local URL. B2listen uses Cloudflare’s free Quick Tunnels feature to proxy traffic from an internet-accessible URL to a local endpoint.
  • B2 Browser Upload shows you how to upload files directly to Backblaze B2 from JavaScript code running in the browser, with sample code for both the Backblaze B2 Native and S3-compatible APIs.
  • The Backblaze B2 Zip Files Example implements a simple Python web app, using the Flask web application framework and the flask-executor task queue, that can compress a set of files located in Backblaze B2 into an archive, also stored in Backblaze B2, without using any local storage.

We’ll write more about these, and other, as yet unreleased, open source projects, over the coming weeks and months, but, if you’d like us to prioritize any of the above three repositories, or any of our other projects, let us know in the comments!

The post Do More with Backblaze B2: A Tour of the Backblaze GitHub Repositories appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Backblaze Network Stats: Ingress Trends and What They Tell Us About Backup Behaviors

Post Syndicated from Brent Nowak original https://www.backblaze.com/blog/backblaze-network-stats-ingress-trends-and-what-they-tell-us-about-backup-behaviors/

An image with a background pattern of trend lines and the words "Network Stats Ingress rends and what they tell us"

Every day, thousands of Backblaze customers create and update files. These changes make their way into our system to be securely stored. Sometimes they are sent to us immediately, while other times the differentials are batched up into a job that runs at a scheduled time. 

In this post, I’m sampling three points in our network where we take in a lot of ingress traffic off of the internet, and we’re going to explore some of the trends that we see. 

Reading the ingress tea leaves

So, why do we care about ingress trends? In short, it helps us with capacity planning, and it also tells us a lot about how people use cloud storage. We often think of planning in longer terms—weeks, months, or years. Here I wanted to focus on some of the patterns that we see during a shorter period; for example, a single day or a significant date, like the end of the calendar month. There are some interesting patterns we see in our client behavior that keep us on our toes when we are performing capacity planning.

We currently have two product offerings that have different usage and traffic patterns:

  • Backblaze B2 Cloud Storage: Ingress and egress, high variance in traffic levels throughout the day, hour, and at the start of month. 
  • Backblaze Computer Backup: Heavy ingress, with a small variance in traffic levels during the business day or weekday vs. weekend.

Since humans are using our system, we see very human quirks in our traffic profiles. For example, we humans like round numbers! We notice that a lot of backup jobs kick off at midnight local or UTC, or fire off at the top of the hour, or trigger on the first of the month. This means we see spikes of network traffic during these periods. Additionally, a lot of new content gets created during the day and then queued up to be uploaded to us in an overnight backup job.

Scope and terms

Today we’re going to look at ingress traffic, which means we’re monitoring uploads from both Backblaze Computer Backup and Backblaze B2 into our environment. We’ll save downloads, traffic coming out of Backblaze, for analysis in future posts.

One common term that you’ll see on our graphs in the 95th percentile. The 95th percentile number is a point where 95% of all measurements are under and only 5% are over. This is a very typical method to use for monitoring, billing, and trend analysis in the telecom industry. It maps to a standard bell curve, and tells you that you’re capturing the vast majority of usage for planning purposes.

A chart displaying a bell curve and percentiles
A standard bell curve. Source.

In one of our monitoring systems, we are sampling and recording the utilization on our network links and computing a 95th percentile over a five minute period.

With these items defined, let’s get into the data with some charts!

Sample 1: One-month trend

In this first sample, we see that the majority of our daily traffic falls within a nice range. What stands out here is the clock tick over from February to March, where we see a spike of ingress traffic that is outside the expected daily range.

A chart displaying a sample of ingress trends over one month.

Taking that same dataset, let’s take a closer look at the end of the month and zoom in on the calendar change into March.

Adding a vertical red line on 00:00 UTC where the month changes over, we see that there must be a lot of automated jobs that kick in right at the clock changeover into the new month.

A chart showing ingress trends over 7 days.

Sample 2: Top of the hour

Taking a look at another traffic sample from another point in our network, we see very distinct traffic patterns on the top of almost every hour.

A chart showing ingress trends over 24 hours

Sample 3: Pacific Time Zone working hours

Here’s a sample of traffic in our US-West region. During the business day on the West Coast, we see a lull in traffic, with a pickup after the business day is done. This makes sense to us as there are jobs that backup daily content that start to send traffic to us overnight.

A chart showing ingress trends over three days.

What does this mean for you?

It’s very interesting to see the impact of humans in our network traffic and the patterns that emerge. Generally we humans create and modify things during the day, and we like to back them up over night for safekeeping. And we also like round numbers—people tend to send data at the top of the hour, midnight, or end of the month. 

All of these elements are very important in how we, at Backblaze, capacity plan and balance traffic over transit links. We do a lot of work to make sure that no matter what time of day or day of the month, you can reliably get your data into Backblaze.

But, you might also look at this data and take away a meaningful conclusion: Much like choosing to go to the grocery store at 10:30 a.m. on a Tuesday versus fighting the after-work rush at 6:00 p.m., scheduling jobs on the 15, 30, or 45 minute mark or mid-month instead of at the end of the month would mean you’re up against less traffic, which is never a bad thing (and it also smooths out our ingress, which we wouldn’t be mad about either).

At the end of the day, however you choose to schedule your jobs works for us. We’re just glad we’re able to store and protect our customers’ data reliably and affordably, and we’re happy to pass along any tips and trips for a better, less congested, backup experience as well.   

Thanks for reading, and stay tuned for more graphs and commentary on how we strive to build a reliable, scalable, and forward looking network to serve our customer’s needs.

The post Backblaze Network Stats: Ingress Trends and What They Tell Us About Backup Behaviors appeared first on Backblaze Blog | Cloud Storage & Cloud Backup