Tag Archives: Media Workflow

Backblaze B2 x Suite Studios: S3 Native File Streaming Turns B2 Cloud Storage Into a High-Performance Drive

Post Syndicated from Dave Simon original https://www.backblaze.com/blog/backblaze-b2-x-suite-studios-s3-native-file-streaming-turns-b2-cloud-storage-into-a-high-performance-drive/

A gradient background with Backblaze and Suite Studios logos and the words "S3 Native File Streaming"

Announcing a new integration between Backblaze B2 and Suite Studios’ S3 Native File Streaming that brings together scalable object storage and the familiar experience of working from a local drive.

Available today with Backblaze B2, the integration allows teams to mount a B2 bucket through Suite Studios and work with files as if they were stored on a high-performance NAS. Suite streams only the parts of each file an application needs, rather than requiring users to download entire datasets first.

Behind that experience, the data remains in Backblaze B2 as standard S3-compatible objects.

Ready to get started now?

To put Suite S3 Native to work on B2, contact Backblaze Sales or your Backblaze reseller partner. We can help validate your architecture, plan a proof of concept, and evaluate migration support for your existing data.

Your B2 bucket becomes the working file space

An existing Backblaze B2 bucket can now be used directly as a Suite file space. There is no separate storage environment hidden inside Suite and no proprietary segmentation happening in the background.

The relationship between the file system and the bucket remains straightforward:

  • One file in Suite maps to one object in B2.
  • The folder structure in Suite matches the structure in the bucket.
  • Files remain standard, whole objects.
  • B2 remains the system of record.
  • Suite provides the high-performance file access layer.

For users, cloud storage behaves more like a shared NAS experience. For IT, the underlying data remains in a storage platform the organization owns and controls.

If your files are already stored in B2 as standard objects, Suite can connect to the bucket and make them available through its mounted drive. There is no need to create another copy, convert the data, or run a separate ingest into Suite.

One dataset, multiple ways to use it

The immediate opportunity is media production, where teams work with large files across editing, media management, transcoding, automation, archive, and distribution.

An editor can open high-resolution media in Adobe Premiere Pro through the Suite drive. At the same time, iconik or another MAM can index the library, Telestream Vantage can process the source files, and automation can respond to new objects written into B2.

Each application works with the same underlying media.

But this is not exclusively a media workflow. The same model has practical applications anywhere teams need to work with large cloud datasets through file-based desktop tools:

  • Life sciences and biotech: Make genomic sequencing, microscopy, medical imaging, and instrument-generated data accessible to researchers without maintaining full copies at every location.
  • Geospatial and earth observation: Work with satellite imagery, drone captures, LiDAR scans, and GIS datasets while keeping source files centrally stored.
  • Engineering and design: Give teams file-based access to CAD assemblies, simulations, 3D models, digital twins, and high-resolution scans.
  • Research and higher education: Create shared access to large scientific datasets for distributed teams while maintaining a common storage foundation.

These are emerging applications for the architecture rather than packaged Suite solutions today, but the underlying opportunity is clear: Large datasets become much more useful when people and applications can access them without moving them into another storage silo.

Built for active data

Media, scientific data, and geospatial imagery rarely sit still. Files are opened, reviewed, processed, moved, analyzed, and shared throughout their lifecycle.

Backblaze B2 provides always-hot, S3-compatible object storage with straightforward pricing and free egress up to three times average monthly storage, plus unlimited free egress through select CDN and compute partners.

That makes B2 a strong foundation for data that needs to remain active and accessible. Suite adds another way to put that data to work by making a B2 bucket accessible through a high-performance file interface.

Available today, with migration support

Backblaze B2 is available today for Suite S3 Native workflows.

If your data is already in B2, you can use an existing bucket as your Suite file space. If it currently resides in another cloud, on a NAS or SAN, or on tape, Backblaze can help plan and execute the move.

Organizations making a qualifying commitment can receive assisted migration into B2 through our Universal Data Migration program.

Bring the data into the storage platform you want to keep. Let cloud applications access it through S3. Let people access it through a high-performance drive.

One dataset. One storage foundation. Multiple ways to put it to work.

The post Backblaze B2 x Suite Studios: S3 Native File Streaming Turns B2 Cloud Storage Into a High-Performance Drive appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Introducing Genblaze: A Python SDK for Generative Media Pipelines

Post Syndicated from Jeronimo De Leon original https://www.backblaze.com/blog/introducing-genblaze-a-python-sdk-for-generative-media-pipelines/

Isometric illustration of multiple monitors displaying pixelated data visualizations in a purple, blue, and red color scheme, representing generative AI media pipelines.

A year ago, a good video model was a novelty. Today there are at least six worth using, and most of the teams we talk to are wiring up two or three of them into the same product, alongside image models, voice synthesis, and music generation. The hard question isn’t whether you can generate this kind of media. It’s how to build a pipeline that handles five providers without falling over.

That’s why we built Genblaze, an open-source Python SDK from Backblaze for building generative media pipelines: one API across video, image, and audio providers, swappable models, durable object storage, and a SHA-256-verified provenance manifest on every run.

The pipeline is becoming the moat

Models are commoditizing. New video, image, and audio releases drop every couple of months, and each one tends to be the best at one specific thing and middling at the rest. Nobody we work with is betting on a single provider anymore. They build a portfolio and configure fallbacks.

The pipeline is what stays. It’s where you’ve figured out which model handles which shot type and which voice fits which brand. It’s where retry logic and output guards live, and where your audit trail comes from. That work survives the next model release. The prompts you tuned for last quarter’s hero model don’t.

For a pipeline to actually be durable, though, it has to be reactive. Hard-coding one provider, blocking on every step, and returning a single synchronous result is fine for a demo. In production it ages out in weeks. The pipelines that hold up stream progress as events, fan out concurrent work, handle backpressure from slow providers, and let you add a new model with a one-line change.

That’s what Genblaze is designed to be. One pipeline object, every provider behind the same surface, and a new model is one more .step().

A workflow that uses five providers

Here’s a concrete example: producing a short brand film from a one-paragraph brief.

1. Storyboard frames. Lock the visual direction with Seedream 5.0 Lite or FLUX via GMI Cloud, or Imagen on Google.

2. Animate the approved frame. Kling image-to-video on GMI Cloud, Veo on Google, Runway Gen-4 Turbo, or Luma Ray-2. They’re good at different shot types, so we usually try two and pick. Setting chain=True on the pipeline passes the image from step one into the video step automatically.

3. Score and sound design. Music from Stability AI’s Stable Audio or GMI Cloud’s MiniMax. Ambient effects and voiceover from ElevenLabs. LMNT for low-latency text to speech (TTS) when responsiveness matters.

4. Upscale. There’s an upscale step type built in. Route the rendered video through a Replicate upscaler like Real-ESRGAN to hit delivery resolution.

5. Classify and tag. Use a vision-capable chat() call to tag scenes, run brand safety checks, or generate accessibility metadata. Gemini 2.5, GPT-4o, or Llama 3.2 Vision on GMI Cloud all handle this.

That’s five providers across five different model types, defined in one pipeline. The same retry behavior, fallback chains, and provenance manifest apply to every step.

from genblaze_core import Pipeline, Modality
from genblaze_gmicloud import (
GMICloudImageProvider, GMICloudVideoProvider, GMICloudAudioProvider,
)
from genblaze_replicate import ReplicateProvider
from genblaze_google import GeminiChatProvider

run, manifest = (
Pipeline("brand-film", chain=True)
.step(GMICloudImageProvider(), model="seedream-5.0-lite", prompt="...", modality=Modality.IMAGE)
.step(GMICloudVideoProvider(), model="Kling-Image2Video-V2.1-Master", prompt="...", modality=Modality.VIDEO)
.step(GMICloudAudioProvider(), model="minimax-music-2.5", prompt="...", modality=Modality.AUDIO)
.step(ReplicateProvider(), model="nightmareai/real-esrgan", step_type="upscale")
.step(GeminiChatProvider(), model="gemini-2.5-pro", step_type="classify",
prompt="Tag scenes, return JSON with shots, mood, brand-safety flags.")
.run(sink=storage, timeout=900)
)

Swap any step for a different provider and nothing else in the pipeline has to change.

Provenance

Every run produces a canonical, hash-bound manifest that records the provider, model, prompt, parameters, timestamps, and the URI of every asset it produced. You can embed it directly into the output file (.mp4, .png, .jpg, .webp, .mp3, .wav are all supported by the matching media handler), or persist it as a sidecar JSON.

The hash is deterministic, so anyone downstream can verify the file by calling manifest.verify(). The same manifest is replayable: genblaze replay manifest.json reconstructs the run with the same parameters. And because every manifest carries a parent_run_id, you can trace a v3 video back through v2 and v1, including the fork where you tried Runway instead of Kling.

If you’re building customer-facing pipelines, this is what gets you from “we generated this” to “here’s the proof.”

Storage

Assets and manifests land wherever you want. We default to Backblaze B2, which the SDK wires up with ObjectStorageSink(S3StorageBackend.for_backblaze("my-bucket")) and which gives you durable URLs that don’t expire and don’t need credentials to fetch. The same sink works against any S3-compatible store: AWS S3, Cloudflare R2, MinIO.

A few B2 features pair particularly well with this kind of pipeline.

Event Notifications fire to a webhook, queue, or function endpoint when an asset or manifest lands. That gives you a clean way to kick off downstream encoding, indexing, or moderation without polling.

Object Lock lets you write manifests under a retention policy that nobody (not even the account root) can overwrite until the window expires. Combined with the SHA-256 hash inside the manifest, you’ve got cryptographic integrity and storage-layer immutability.

Lifecycle rules handle the cleanup. Final assets and manifests stay around as long as you want them to. Storyboard iterations, rejected takes, and pre-upscale renders prune themselves on whatever schedule you set.

Partnering with GMI Cloud: a unified AI inference platform for open source

GMI Cloud is a unified AI inference platform for open source. It supports LLM, image, video, and multimodal inference through one consistent API. The catalog covers Seedance, Kling, Veo, and Wan for video; Seedream and FLUX for image; MiniMax for music; ElevenLabs voices; and Llama, DeepSeek, and Qwen for chat and multimodal. One API key reaches all of it.

The genblaze-gmicloud adapter maps GMI’s image, video, audio, and chat endpoints onto the pipeline surface and tracks their catalog as new models ship. The first sample app below uses it heavily.

Two sample apps

genblaze-gmicloud-pipeline goes deep on a single provider. A prompt becomes an anchor image via seedream-5.0-lite. You iterate by passing the current image to flux-kontext-pro for reference-based refinement. Once you approve a frame, the app fans out concurrently to three video models (Kling-Image2Video-V2.1-Master, wan2.6-i2v, pixverse-v5.6-i2v). Manifests get written to B2 next to the assets, and the Genblaze integration sits in a single ~100-line file.

genblaze-gen-media-multi-provider-sample is the workflow above end to end. One sentence becomes a narrated, scored, captioned MP4. gpt-4.1-nano writes the storyboard, Imagen 4 produces the keyframes, Decart Lucy or GMI Cloud Kling animates them, NVIDIA Magpie TTS narrates, GMI Cloud MiniMax scores, and ffmpeg composes the final video. Five providers, one pipeline, every artifact ending up in B2 with a verifiable manifest.

Both are MIT-licensed. Clone, fill in .env, run. GMI Cloud docs can be found here. 

Get started

bash

pip install genblaze

That umbrella installs genblaze-core plus the B2/S3 storage backend, which is enough for a working provenance pipeline. Add genblaze[gmicloud], genblaze, or genblaze[all] to pull in providers.

Where this goes

Most of the interesting work in generative media is happening above the models now, in the pipelines that string them together. Whatever model you’re using today probably won’t be your favorite in six months. The orchestration around it is what lasts.

Genblaze is what we built. It’s MIT-licensed and lives at github.com/backblaze-labs/genblaze.

The post Introducing Genblaze: A Python SDK for Generative Media Pipelines appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Backblaze B2 Neo Wins NAB Show 2026 Product of the Year

Post Syndicated from Laquie TN Campbell original https://www.backblaze.com/blog/backblaze-b2-neo-wins-nab-show-2026-product-of-the-year/

A decorative image showing the Backblaze logo and various digital elements.

NAB Show 2026 wrapped up last week in Las Vegas, and we left with something special in hand: the NAB Show Product of the Year Award in the Cloud Computing and Storage category—this time for Backblaze B2 Neo.

It’s a meaningful recognition, and one that reflects where we see the media and AI infrastructure market heading. Here’s a look at what the recognition means, and why B2 Neo matters.

What this recognition means

Winning the NAB Product of the Year Award reflects something we genuinely believe: that storage infrastructure is a foundational capability for modern media and AI platforms, not an afterthought or a separate vendor relationship to manage.

The NAB Show brings together the best of the media and entertainment industry, and having B2 Neo recognized in this context—among platforms solving real, production-scale problems across streaming, OTT, AI-driven media processing, and large-scale content delivery—is meaningful validation that the approach resonates.

B2 Neo launched in February 2026 and is already supporting production workloads including AI training pipelines, high-performance computing environments, and large-scale media delivery. The response from platform providers has reinforced what we know: organizations want to offer integrated, high-performance storage without building it from scratch, and they want the economics to make sense.

What is B2 Neo?

B2 Neo is a high-performance, S3-compatible cloud object storage solution purpose-built for platforms running data-intensive media and AI workloads. But describing it simply as “cloud storage” undersells the point.

The key distinction: B2 Neo is a white-label service. Rather than selling storage directly to end users, B2 Neo enables platform providers—like media workflow vendors—to offer fully integrated storage under their own brand. Partners launch their own storage service with custom endpoints, pricing, and user experiences, without having to build or operate the underlying infrastructure themselves.

The result is that platforms can go from “we don’t offer storage” to “we have a native, high-performance storage tier” in weeks rather than years, with none of the capital investment or engineering overhead that building it in-house would require.

Why it was built

The problem B2 Neo addresses has been growing for years, but it’s become acute as streaming, OTT, and AI-driven media workflows scale up.

Compute has gotten fast, distributed, and relatively affordable. GPU clusters, edge networks, and CDNs can all handle increasingly complex workloads. But storage has often lagged behind—fragmented across providers, expensive to move data in and out of, and either too costly or too operationally burdensome to build in-house.

The consequence is real: GPU clusters sit idle waiting on data. Streaming pipelines bottleneck on access speeds. Media organizations duplicate content across storage systems because no single layer integrates cleanly into the rest of the stack.

B2 Neo was designed to remove that bottleneck. It delivers up to 1Tbps of throughput to ensure that compute resources—GPU clusters, streaming systems, edge delivery networks—are never waiting on storage. It combines that performance with Backblaze’s 17+ years of operational experience at exabyte scale, and wraps it in an API-first architecture that plugs directly into partner platforms.

How it works

From a technical standpoint, B2 Neo delivers high aggregate throughput using cost-efficient, disk-based infrastructure with strategically deployed flash layers—a write-through cache design that captures the performance benefits of flash without the cost and scalability limitations that come with an all-flash architecture at the multi-petabyte scale that media and AI workloads require.

For workloads where throughput matters as much as latency—moving large video files, training AI models, serving content at scale—this approach is particularly effective. It allows platforms to maintain a centralized data repository and efficiently deliver data to compute providers, edge networks, and CDNs without duplicating data across storage systems.

API-driven provisioning lets partners programmatically create and manage storage accounts, permissions, and billing within their existing systems. Whether a partner is running an OTT platform, a media asset management system, or an AI training pipeline, B2 Neo integrates as a native extension of that environment rather than an external dependency to work around.

Included egress and free API calls round out the picture, eliminating the usage-based fees that typically make storage decisions financially complicated.

What’s next

This is a product that will keep evolving alongside the media and AI infrastructure landscape. We’re working closely with early partners to expand B2 Neo’s capabilities—performance, integration depth, provisioning flexibility—and we’ll have more to share as those conversations develop.

If you’re building or operating a platform that would benefit from embedded, high-performance storage, we’d love to talk. Reach out to our team to learn more about what a B2 Neo partnership looks like.

See you at NAB Show 2027!

The post Backblaze B2 Neo Wins NAB Show 2026 Product of the Year appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Meet the Partners Building the Future of Media Workflows with Backblaze

Post Syndicated from Laquie TN Campbell original https://www.backblaze.com/blog/meet-the-partners-building-the-future-of-media-workflows-with-backblaze/

A decorative image showing the Backblaze logo amidst film lights and cameras.

Modern media workflows don’t run on storage alone. They run on ecosystems—tightly integrated stacks of tools that ingest, process, analyze, move, review, and distribute content at scale. The companies we partner with aren’t just integrating with Backblaze; they’re building on it to solve real, specific problems that media teams face every day: archives that are impossible to search, file transfers that collapse over distance, review cycles that slow production to a crawl, compliance workflows that can’t keep up with library growth.

At NAB Show 2026, we’re bringing ten of those partners into booth N1259 to share what they’ve built. But the stories they’re telling aren’t just for Las Vegas—they’re for any media team trying to understand what a modern, cost-efficient, deeply integrated workflow actually looks like in practice.

Here’s a look at each partner, the problem they solve, and why it matters.

Imaginario AI: From Archive to Action

Presenter: Jose Puga, CEO and Co-Founder, Imaginario AI

Most video archives are passive. Content sits in storage, cataloged by someone who had time to do it years ago, effectively invisible to the people who could use it today. Imaginario AI flips that model.

Jose Puga’s session, “From Archive to Action: How AI Is Turning Your Video Library Into a Revenue Engine,” frames the shift from passive storage and cataloging to intelligent systems that actively surface, repurpose, and monetize content. The talk covers how marketing teams can accelerate campaigns, post-production teams can shortcut assembly, and compliance workflows can move from reactive to automated.

Imaginario is a multimodal video agentic platform that understands video in a human-like way—recognizing sounds, speech, and visual scenes without requiring time-based metadata. The platform is trusted by Warner Bros. Discovery, Sony Music, and Universal Pictures, and has won back-to-back IBC Best of Show honors in 2024 and 2025.

The Backblaze integration means content stays where it lives—no migration, no friction. As Jose puts it: “Backblaze provides our clients a scalable, reliable cloud layer that eliminates the friction of manual data transfers. Our native integration saves video teams dozens of hours by keeping content on Backblaze while unlocking high-speed AI analysis, retrieval, and repurposing in media and entertainment.”

Suite Studios: S3 Native File Streaming

Presenter: Jay Maxwell, Co-Founder & CPO, Suite Studios

Remote and distributed production teams have wrestled with the same problem for years: How do you collaborate on large media files when your team is spread across the globe? Suite’s answer is S3 Native File Streaming on Backblaze B2. The stack makes working with cloud object storage all-around easier, enabling teams to read and write data as standard objects without copying, syncing, or transferring.

Jay Maxwell’s session explores how global teams can instantly access and collaborate on large media files from anywhere—eliminating delays and accelerating production timelines. No syncing, no waiting, no workarounds. Just files that behave the way you need them to, wherever your team happens to be.

TwelveLabs: Unlocking Archive Value with Video AI

Presenter: Jordan Woods, Senior Solutions Architect, TwelveLabs

There’s a pattern across media organizations of all sizes: years of valuable archived content sitting effectively invisible because manual cataloging doesn’t scale. TwelveLabs makes that content searchable and monetizable.

Jordan Woods’ session, “Unlocking Archive Value with TwelveLabs Video Intelligence,” shows how pairing Backblaze’s cost-efficient storage with TwelveLabs’ video AI gives organizations a practical path to turn dormant archives into searchable, monetizable assets.

As Danny Nicolopoulos, Head of Strategic Partnerships at TwelveLabs, explains: “Media companies are sitting on years of valuable archived content that’s effectively invisible because manual cataloging doesn’t scale. Pairing Backblaze’s cost-efficient storage with TwelveLabs’ video AI gives organizations a practical path to turn those dormant archives into searchable, monetizable assets.”

Tillered: Full Speed Cloud Storage Over Any Distance

Presenters: Davey Goode, Founder & Stephen Ceci, Commercial Lead, Tillered

Physics is an undefeated opponent. Move data over long distances and throughput drops—no matter how fast your storage is or how much bandwidth you have. Tillered is built to remove that distance penalty.

The session, “Backblaze B2 Accelerate with Tillered: Full Speed Cloud Storage Over Any Distance,” demonstrates how the B2 Accelerate product brings Tillered’s acceleration technology to Backblaze B2, with transfers up to 34x faster as a result. No simulations—just live transfers with real results, showing what it looks like when enterprises can move data across any distance without adding bandwidth or changing workflows.

Davey Goode founded Tillered after repeatedly running into the same issue building large-scale connectivity infrastructure: No matter how much bandwidth was available, performance collapsed over distance. This session is the solution he built.

Telestream UP.Review: Decide Faster

Presenter: Sebastian Manemann, Senior Director of Product Management, Telestream

Capture, storage, and distribution have gotten faster. Review hasn’t kept up. Proxies, downloads, duplicated files—the approval workflow often undoes the speed gains made everywhere else in the pipeline.

Sebastian Manemann’s session, “Decide Faster: Real-Time Review, QC, and Delivery with Telestream UP.Review and Backblaze B2,” demos how Telestream UP.Review enables real-time, high-resolution playback and QC directly on media stored in Backblaze B2 without moving or duplicating files.

By keeping content in Backblaze as the central storage layer, teams can review instantly, validate quality, and move to delivery faster—all while maintaining a single source of truth across the workflow. As Sebastian frames it: “When you eliminate duplication and review directly from storage, you don’t just move faster—you operate smarter.”

Qencode + Sardius: A Multi-Vendor M&E Workflow in Practice

Presenters: Murad Mordukhay, CEO, Qencode, and Jason Shore & Ari Burt, Sardius Media

This one is different from the others—it’s not a product demo; it’s a case study. Sardius Media rebuilt their media pipeline around a race model: Multiple storage providers write in parallel, and the fastest result wins.

The session breaks down how Backblaze wins approximately 80% of those races, with Qencode orchestrating the encoding layer across the pipeline. It covers what the production data actually shows, and what Sardius would do differently if they were designing the workflow from scratch today.

Qencode uses machine learning to reduce file sizes by an average of 60% without sacrificing quality. Their CEO, Murad Mordukhay, sums up the partnership plainly: “The best partnerships are when two companies solve different halves of the same problem. Backblaze handles storage with the kind of reliability and transparency that perfectly aligns with how we think about transcoding. No surprises, no lock-in, just infrastructure that earns trust by performing every single day.”

HiScale: Orchestrating Media Across the Stack

Presenter: Christoph Jurkuhn, CEO, HiScale

Media workflows break down not just because of bad tools, but because of coordination failures between good ones. Files don’t sync. Teams duplicate work. Availability lags behind where content actually needs to be.

Christoph Jurkuhn’s session, “The Hidden Layer: Orchestrating Media Across the Stack with HiScale and Backblaze,” shows in a live demo how HiScale orchestrates media movement across distributed environments while Backblaze B2 provides the durable, scalable storage layer underneath. Files move, sync, and become available across teams and tools without delays, duplication, or manual intervention.

“Backblaze is built for straightforward, cost-efficient storage and HiScale builds on top of that to orchestrate and process your media. It’s a natural fit for modern media workflows.”

Iconik: Control Your Content

Presenter: Jeremy Strootman, Media Workflow Consultant, Iconik

At a certain scale, the problem isn’t creating content; it’s controlling it. Files get lost, search slows to a crawl, and archives become liabilities instead of assets.

Jeremy Strootman’s session, “Control Your Content: Turning Media Chaos into Operational Advantage,” demos how Iconik and Backblaze B2 give teams operational control over their media: making content instantly searchable, accessible, and reusable across the entire workflow.

With a foundational background in storage and archiving, Jeremy has spent over two decades helping content creators maximize efficiency and productivity across the entire media lifecycle, from ingest to archive. His perspective: “Backblaze gives us the scalable foundation; Iconik gives teams control over how that content is actually used.”

ToolsOnAir: Modern Broadcast Workflows on Backblaze

Presenter: Peter Steiner, Chief Business Officer, ToolsOnAir

Peter Steiner’s session, “Record, Store, Play: Modern Broadcast Workflows on Backblaze,” brings ToolsOnAir’s deep broadcast expertise to bear on what it looks like to build a complete ingest-to-playout workflow with Backblaze B2 as the storage foundation.

ToolsOnAir has been building Apple-based broadcast solutions for over a decade, with deployments across broadcast, ingest, and storage workflows worldwide. This session is for anyone running live or near-live operations who wants to understand what a modern, cloud-native broadcast stack actually looks like in practice.

Mixpeek: AI-Powered Media Compliance at Scale

Presenter: Ethan Steininger, Founder & CEO, Mixpeek

The final session tackles a problem that’s only growing: As video libraries scale into the billions of assets, compliance workflows built for smaller operations don’t hold.

Ethan Steininger’s session, “What You Miss Can Cost You: AI-Powered Media Compliance at Scale on Mixpeek and Backblaze B2,” shows how Mixpeek’s multimodal AI infrastructure platform transforms unstructured content—video, images, audio, and documents—into searchable, programmable assets through a unified API.

Before founding Mixpeek, Ethan led search at MongoDB, and today Mixpeek powers enterprise workflows across media, adtech, healthcare, and brand safety, with core technology spanning feature extraction, multimodal retrieval, and a custom-built distributed vector store engineered for billion-scale workloads.

The Bigger Picture

Ten companies, one through-line: storage that integrates cleanly across the entire media stack changes what’s possible. As I put it in my article for Post Perspective

What we are seeing is a broader realization that infrastructure decisions directly shape how teams build and operate. When pricing models penalize access or iteration, teams naturally limit how often they experiment or how much data they retain. That has a direct impact on product velocity and long-term value creation.

Backblaze didn’t have to react to this shift; it’s how we have always approached the market. Our cost model removes barriers like egress and transaction fees so teams can operate freely. That allows media organizations to focus on where value is actually created—whether that is content, audience engagement, or new AI-driven capabilities—while still maintaining craft excellence.

When your foundation is cost-efficient, S3-compatible, and built for reliability at scale, every tool in the ecosystem above it gets to do its best work. That’s what we mean when we talk about “building the future of media workflows”—not just that Backblaze stores your files, but that it enables the ecosystem built on top of it.

Join Us at NAB Show 2026

We’d love to show you around. Whether you want to catch one of the in-booth presentations, sit down for a workflow consultation, or talk through your specific storage and integration challenges, our team will be on-site all week.

Visit our booth N1259 or book a meeting at backblaze.com/nab2026.

NAB Show 2026 runs April 18–22 in Las Vegas, NV.

The post Meet the Partners Building the Future of Media Workflows with Backblaze appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Archiving: The Steady Driver of Media & Entertainment Storage

Post Syndicated from Laquie TN Campbell original https://www.backblaze.com/blog/archiving-the-steady-driver-of-media-entertainment-storage/

A decorative image showing media icons on a gradient background.

Industry research consistently shows that archiving and preservation remain the largest drivers of storage demand in media and entertainment workflows. As of 2024, archiving—including both new and historical assets—accounts for the majority of digital storage capacity. 

This reflects an ongoing reality: Every production adds new terabytes of content, and studios/vendors are responsible for keeping it safe and usable long-term. And, for many M&E teams, traditional LTO tape libraries represent a cumbersome way to manage vast (and growing) archives. 

Increasingly, the decision is less whether to adopt cloud, and more how to use it responsibly. For some, that means hybrid systems that balance performance and scalability. For others, particularly smaller studios, cloud may become the backbone of both active and deep archives.

Free ebook: Why Media Workflows Are Embracing Cloud Storage—On Their Own Terms

Cloud media workflows are quick to promise a solution, but it’s more important for you to learn how to navigate. Read our ebook on how to use the cloud to best serve you and your team.

Your Media, Your Way

Why archiving dominates conversations—and what makes it so complex

Long-term preservation isn’t a “set-and-forget” task—technology evolves, file formats age, and migration becomes as essential as storage itself. Meanwhile, the shift to 4K, 8K, HDR, and immersive content means productions routinely generate petabytes of material. 

The challenge isn’t just volume, but ensuring ongoing integrity, accessibility, and migration compatibility over decades. That makes both current trends in file creation and future-proofing archives an active task. 

While the challenge can look different to different types of M&E teams, there are benefits for all of them:  

  • For editors and post-production teams, active archives keep high-resolution footage readily available, eliminating the frustration of digging through cold storage when a quick edit or repurposing request comes in.
  • For media asset managers, they transform archives into searchable, metadata-rich repositories that reduce retrieval time and prevent costly duplication of content.
  • For executives and producers, active archives protect past investments by making legacy assets easily accessible for remonetization in new markets, remasters, and marketing campaigns.
  • For IT and workflow engineers, they provide automated tiering and integration across on-prem and cloud systems, ensuring scalable performance without ballooning infrastructure costs.

Still, a recent NAB survey showed that archive capacity remains a challenge for 85% of respondents. Searchability is another weak spot, with some teams still relying on spreadsheets.

Why cloud adoption has been cautious

Although cloud storage offers flexibility, adoption in the M&E industry has been measured. Common concerns include:

  • High egress costs: Many providers charge significant fees for retrieving archived data. For media workflows that often involve moving large files in and out of storage, these costs can add up quickly.
  • Performance concerns: Latency and bandwidth limitations can disrupt workflows, especially in post-production environments that rely on fast access to high-resolution files.
  • Unpredictable workflows: Unlike enterprise archives where files may be rarely accessed, media archives are often “active.” Teams may suddenly need terabytes of content for a remastering project or marketing campaign. Cloud pricing models built around cold storage don’t always align well with this reality.
  • Trust and security: Especially in the early years of cloud, concerns around data sovereignty, intellectual property protection, and compliance slowed adoption. While cloud providers have strengthened their credentials in these areas, trust remains a consideration.
  • Established investments in on-prem: Many organizations already have significant capital invested in tape libraries, network attached storage (NAS), storage area network (SAN) systems, or colocation setups, making the shift to cloud a long-term transition rather than an overnight change.

How the cloud can help

The shift from “traditional” production to newer technologies in content filming and creation—including both hardware and software tools—leaves many M&E teams with several, competing demands for their tech stacks. Cloud workflows can offer significant benefits for scalability, searchability, and budget management.

Elastic capacity

Cloud removes the need for large upfront capital investments and scales as archives grow. For organizations with fluctuating storage needs, this flexibility is particularly valuable.

Cost-tiering options

Cloud services now offer multiple archival tiers—from “hot” to “deep archive”—allowing teams to balance cost with access needs. Combined with lifecycle management policies, this helps align budgets with actual usage.

Hybrid approaches

The most common strategy today is hybrid: keeping frequently accessed assets on-premises or in private cloud, while offloading less active content to public cloud. Surveys show hybrid adoption has grown significantly in the last five years, with expectations that it will continue to rise.

Collaboration and accessibility

For global teams, cloud improves accessibility. Editors, producers, and marketing teams in different regions can access the same archival assets without relying on physical transfers, VPNs, or duplicated storage.

AI-enabled metadata

Cloud platforms also support AI and ML services that enrich metadata. This transforms archives from passive repositories into searchable, discoverable libraries—unlocking new value from existing content.

The future of media archiving is in the cloud

The move to cloud is gradual, shaped by cost, performance, and workflow realities. Yet the volume and importance of archives—and cloud-based workflows—continue to grow. When paired with thoughtful strategies, cloud storage offers a flexible way to manage that growth while unlocking new creative value.

By designing storage approaches that balance innovation with practicality, M&E teams can ensure archives remain accessible, secure, and ready to support the next generation of storytelling.

The post Archiving: The Steady Driver of Media & Entertainment Storage appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Stack to Win: A Powerful Solution for Sports Media Production

Post Syndicated from Dave Simon original https://www.backblaze.com/blog/stack-to-win-a-powerful-solution-for-sports-media-production/

A decorative image showing the text Stack to Win with Boomer Esiason. In the background, the logos for Backblaze, Suite Studios, and Iconik are displayed on media screens.

I recently joined an incredible group of thought leaders for a panel discussion on the future of sports media. Hosted by sports commentator and former NFL MVP Boomer Esiason, our Stack to Win panel featured Jeremy Strootman from Iconik, Jay Maxwell from Suite Studios, the NFL’s VP of Broadcasting Mike North, and me—Dave Simon from Backblaze. Together, we explored the complexities of modern sports content creation and how our integrated cloud-native solutions from Backblaze B2, Iconik, and Suite offer a powerful blueprint for radically streamlining workflows and unlocking new opportunities for efficiency, speed, and monetization.

The traditional, linear model of sports media production is a thing of the past. It’s been completely changed by new technology and a shift in what fans expect. Today, media teams are in a real-time battle for attention against every other form of entertainment. This new world demands a different kind of setup, one that’s built for the cloud and designed to handle the entire media lifecycle. The solution we’ve built, a powerful combination of Backblaze, Iconik, and Suite Studios, is exactly that. It’s the playbook for staying ahead.

Watch the full interview

There’s so much more that we could summarize in just one blog post. Check out the full video below:

The (data) problem

Game day content is immense—we’re talking 6–7TB of data nightly. In the past, this was a logistical nightmare. As Jeremy Strootman from Iconik pointed out, “It used to be we’d get a hard drive and I’d get a hard drive, and we made sure that we just took different flights on the way home. It was literally that archaic.” When speed is everything, old methods like shipping hard drives are a huge liability.

This pressure comes from fans who have an insatiable appetite for content across every platform imaginable. They expect teams to produce their own content in real-time for streaming and social media. For many, the “second screen” is now the main screen, with 73% of fans using mobile apps for real-time updates during live events. If your workflow is slow, you’ve already lost the competition.

The definition of sports content has also expanded. It’s no longer just about the game itself, but also the stories around it—the players’ lives and the team’s entire ecosystem. Jay Maxwell of Suite Studios captured this perfectly:

The product is not just what’s on the field anymore. It’s also what’s going on in these, you know, athletes lives, what’s going on in the peripheries of the team and the organizations.
—Jay Maxwell, Co-Founder and Chief Product Officer, Suite Studios

This includes pop culture crossovers, fantasy sports, and in-game betting, all of which demand instant video highlights.

A great example of this is when Eagles wide receiver AJ Brown was spotted reading a book called “Inner Excellence” on the sidelines. The moment went viral, and the book, which was previously ranked 585,000 on the bestseller list, vaulted to number one instantly. As the NFL’s Mike North noted, this is how fans can instantly “go deeper” and connect with their favorite players. The ability to capture and distribute these moments instantly is a fundamental requirement for success.

A modern technology stack

An integrated, cloud-native tech stack provides a seamless workflow that removes risk and speeds up the content pipeline. It’s a powerful combination of three key layers:

1. Foundation: The active cloud archive

Modern media workflows are built on a cloud storage foundation that replaces old systems like tape libraries and shelves full of hard drives. The key is an active cloud archive that gives you instant access to your footage. This eliminates the costly delays of older solutions and offers predictable costs, so you never get hit with surprise fees when you need to access your own content.

2. Intelligence: Media Asset Management (MAM)

This is the smart layer that makes your vast archive searchable and valuable. Instead of producers manually sifting through hours of footage, a multimodal AI search engine can find the exact clip they need in seconds. As Dave Simon explained, you can use a natural language search to describe exactly what you’re looking for, such as “Jerry Rice catching a ball over his left shoulder wearing a white jersey”. AI tools in a media stack can automatically transcribe interviews, search for specific quotes, and even identify abstract concepts like emotion or reframe a video for different social media platforms.

3. Accelerator: Real-time cloud editing

This component handles the final stage of production, allowing editors to access high-resolution media without a download delay. This technology streams data directly from the cloud, so editors can start working immediately. This is how a remote team can instantly cut and create content from footage uploaded on the field. 

The real magic is all of these elements combined: A clip is only useful if an editor can work with it right away, and a huge archive is only valuable if you can find what’s in it. This is a single, cohesive system that manages the entire media lifecycle from start to finish.

Reshaping the business of sports

Adopting a modern tech stack empowers rights holders—leagues, teams, and athletes—to manage and distribute content on a massive scale. They can bypass traditional media gatekeepers and build direct relationships with their fans. This opens up several possibilities, such as: 

  • Archive monetization. Vast archives, once a simple cost center, have now become a major source of revenue. With an accessible, intelligent archive, organizations can unlock new revenue streams.
  • Licensing storefronts: You can create B2B portals for broadcasters and filmmakers to license and download footage, which essentially creates a self-service revenue engine.
  • Direct-to-consumer (DTC) fan platforms: Launch your own subscription services with exclusive access to historical games and behind-the-scenes content.
  • Free Ad-supported Streaming TV (FAST) channels: Program and launch FAST channels using repurposed archival content.
  • Creator economy partnerships: License parts of your archive to creators to reach new audiences and share in the revenue.
  • Enable the athlete as a media entity. This same technology is behind the rise of athletes as media producers. Today’s players are actively shaping their own stories and building media businesses. The low barrier to entry for these cloud workflows is the foundation of this movement, giving athletes the same scalable tools once reserved for major networks. A great example of this is Peyton Manning’s Omaha Productions, which started as a player-led media company and became a leader in the space.

The future fan experience

This revolution is transforming the fan experience from a one-way broadcast to something personal, interactive, and instant. The future of sports consumption is personalized feeds tailored to individual interests. As Mike North noted, “You don’t really need to watch the game anymore to still be a fan.” For a fan who wants to know everything about a player, a custom feed can be created. For a fantasy football enthusiast, clips and highlights related to their team can be pushed to them in real time.

The experience will also be interactive. Streaming platforms are already using augmented reality (AR) overlays and multi-angle camera views. The next step, powered by AI and accessible archives, is allowing fans to directly ask for content, like, “‘Show me all the Hail Mary plays from this season?’” and instantly get a custom playlist. This shifts passive viewing into active exploration.

For any sports organization, the biggest risk is standing still and maintaining the status quo. As Jay Maxwell put it, “The barrier to entry to try is, you know, cheap if not free.” An integrated, cloud-native workflow isn’t just a competitive advantage—it’s the fundamental requirement for survival and success.

Check out the full solution below:

The post Stack to Win: A Powerful Solution for Sports Media Production appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Backblaze and CHESA: Doubling Down on a Premier Media Workflow Partnership

Post Syndicated from Mary Ellen Cavanagh original https://www.backblaze.com/blog/backblaze-and-chesa-partnership/

A decorative image showing the Backblaze and CHESA logos.

Media workflows have always been complex, requiring seamless collaboration, robust storage, and advanced systems integration. Today, with the explosion of content demands and rapid technological advancements, media organizations need solutions that can scale, innovate, and empower teams to deliver faster and better. 

Backblaze and CHESA, long-standing partners and leaders in media workflow solutions, are doubling down on their relationship with CHESA to elevate creative workflows with a joint go-to-market partnership. This enhanced partnership builds on years of success, combining Backblaze’s high-performance, secure cloud storage with CHESA’s expertise in media technology systems integration to provide even more impactful solutions tailored to the needs of modern media-driven organizations.

Together, we’re continuing to make it easier than ever for organizations to streamline content production, enhance accessibility, and achieve business objectives with greater efficiency. In this blog, I’ll explain the key benefits of this expanded collaboration and highlight how it’s already driving transformative results for clients like the Philadelphia Eagles.

The media workflow challenge

From production studios and broadcasters to professional sports teams and creative agencies, media organizations face a growing list of challenges:

  • Massive data volumes: Video, audio, and other rich media assets require scalable and secure storage solutions to handle terabytes or even petabytes of data.
  • Fragmented workflows: Teams often juggle multiple tools and platforms, leading to inefficiencies and bottlenecks.
  • Access and collaboration: Remote work and distributed teams demand seamless real-time access to media assets.
  • Budget constraints: Organizations need cost-effective solutions that don’t compromise performance or security.

The expanded partnership between Backblaze and CHESA continues to address these pain points head-on by combining best-in-class cloud storage with tailored workflow solutions.

The Backblaze + CHESA solution

Real-world success: The Philadelphia Eagles

One of the most compelling examples of the Backblaze + CHESA partnership is the Philadelphia Eagles’ transition from traditional LTO tape storage to a cloud-based media workflow. With over 800TB under management, switching to cloud storage meant that the team instantly made their data more agile, scoring immediate access to faster content creation and remote workflows. 

“Now I can easily share entire broadcasts by copying and sharing a link from our MAM. No need for FTP downloads or uploading to other platforms. It’s fast, seamless, and ensures everyone can view the content without issues.”
—Stacy Kelleher, Director of Production, Philadelphia Eagles

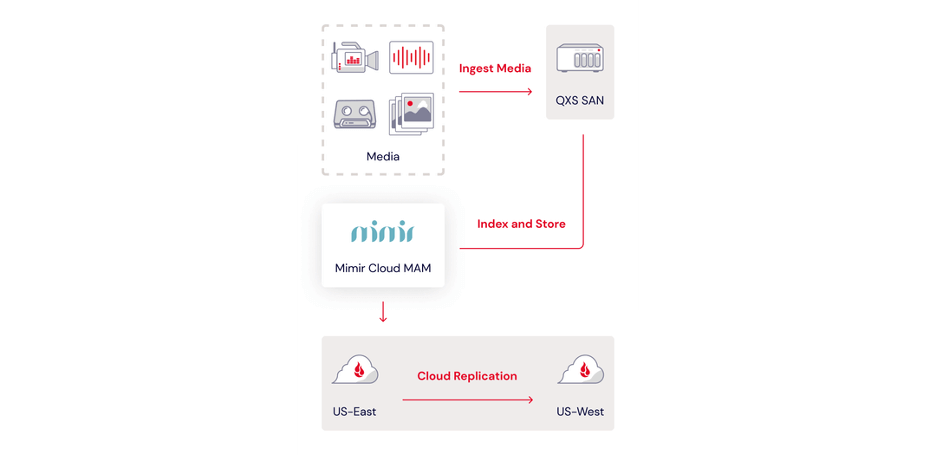
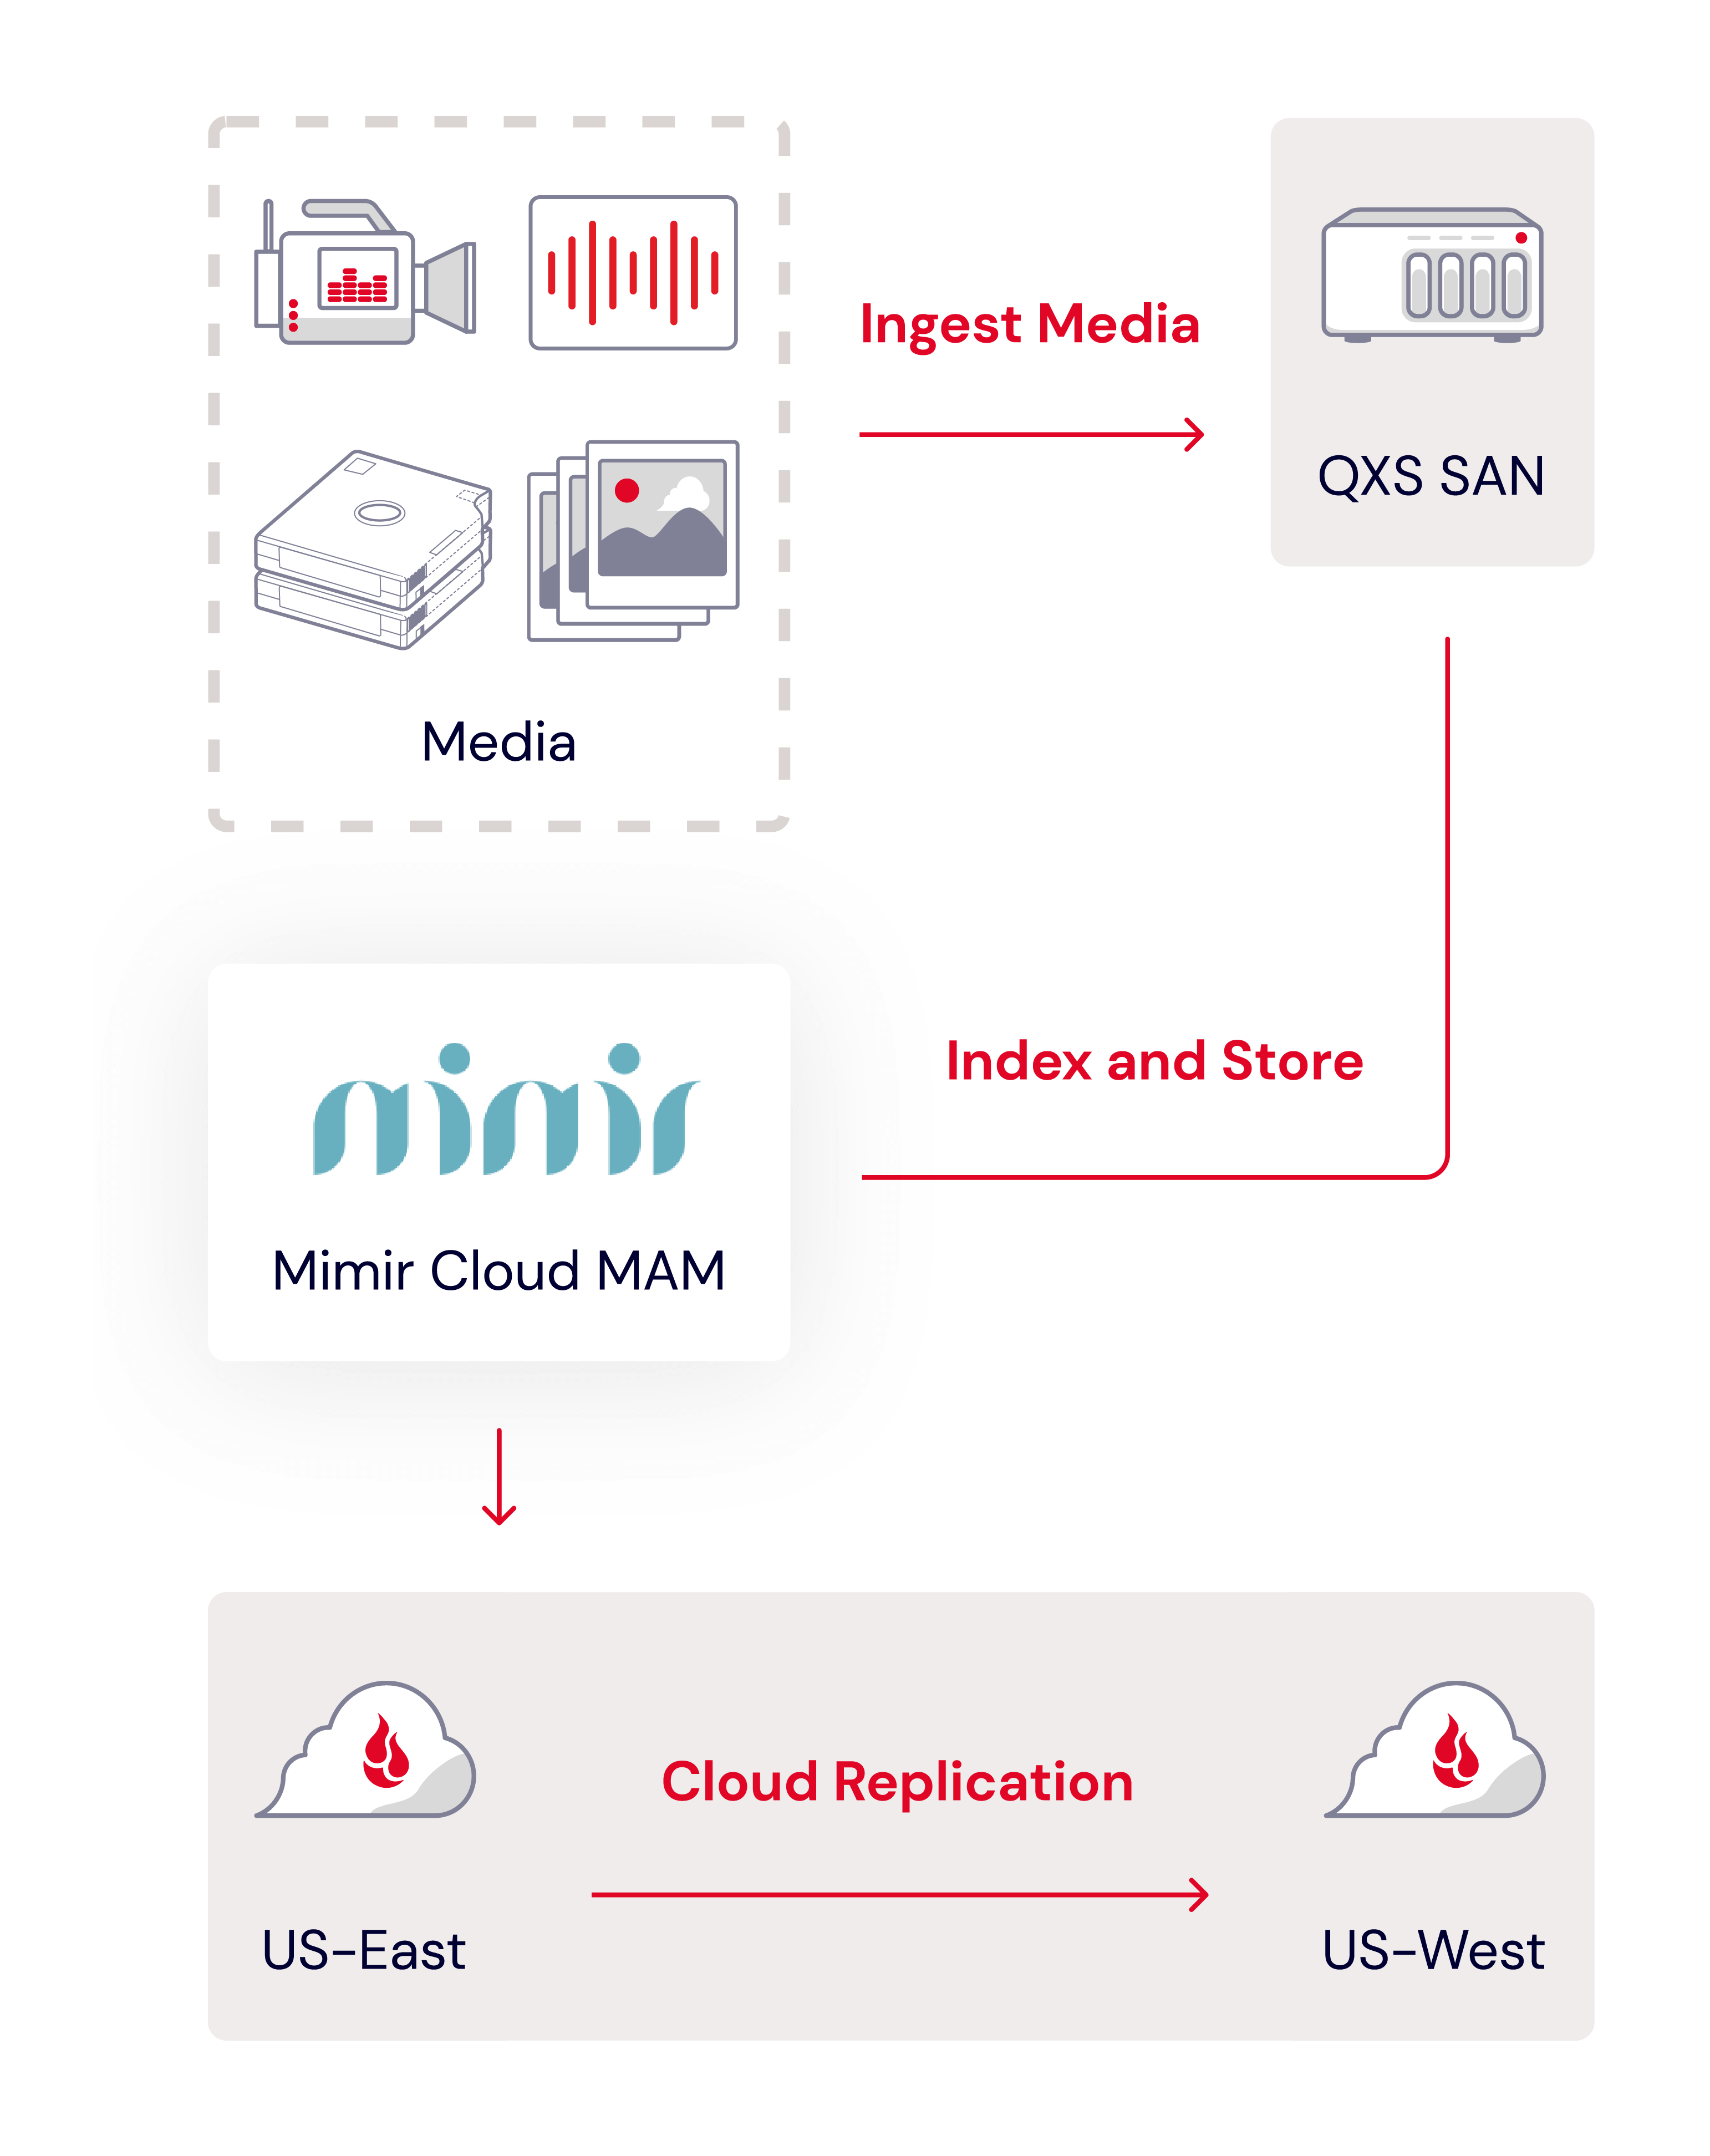
Backblaze B2 integrated seamlessly with the Eagles’ preferred tech stack, which leverages a Quantum QXS storage area network (SAN) and Mimir, a cloud-based video production platform.

The challenge

The Eagles faced significant challenges with their legacy storage system:

  • Limited accessibility: LTO tape storage made it difficult to access archived footage, which hindered content production timelines quickly.
  • Time-consuming processes: Retrieving footage from physical tapes was manual and slow.
  • Scaling limitations: As the team’s content library grew, so did the complexity and cost of managing tape storage.

The solution

By leveraging the expanded capabilities of Backblaze and CHESA’s partnership, the Eagles:

  • Transitioned their extensive media library to Backblaze B2 Cloud Storage.
  • Integrated CHESA’s tailored media workflow solutions for seamless access and collaboration.
  • Gained immediate access to decades of archived footage, enabling faster content creation and improved fan engagement.

The results

The Eagles’ media team now enjoys:

  • Accelerated content production: Instant access to archived footage has streamlined workflows, allowing the team to create engaging content more efficiently.
  • Enhanced scalability: With Backblaze B2, the Eagles can easily scale their storage as their content library grows.
  • Improved fan engagement: Faster production timelines enable the team to deliver high-quality content that keeps fans connected and engaged.

Peripheral content drives revenue through monetized clicks like highlights and select moments. Quick sharing and streamlined proof-of-performance delivery keep sponsors satisfied.”
—Ryan Lakey, Principal Lead, Solutions, CHESA

Accelerated media workflows

Integrating Backblaze B2 Cloud Storage with CHESA’s media workflow expertise has long been a cornerstone of success for media teams. By enhancing this integration, media teams can experience even faster workflows, immediate asset access, and seamless collaboration across tools and teams. By eliminating the delays associated with traditional storage methods, teams can:

  • Quickly retrieve and edit high-resolution media files.
  • Share assets effortlessly with collaborators anywhere in the world.
  • Spend less time managing infrastructure and more time creating impactful content.

Backblaze + CHESA benefits

Scalable and cost-effective storage

Backblaze B2 Cloud Storage offers always-hot, S3 compatible object storage at a fraction of the cost of traditional providers like Amazon S3. This cost-effectiveness, combined with CHESA’s expertise in designing and integrating scalable systems, ensures organizations can:

  • Scale their storage needs as projects grow or shrink.
  • Optimize budgets without compromising on performance.
  • Rely on predictable pricing that avoids surprise costs.

Enhanced data security and accessibility

In the media world, accessibility and security are paramount. Backblaze and CHESA provide solutions that keep media assets safe while ensuring real-time access for production teams. Key benefits include:

  • Secure, encrypted storage to protect sensitive media.
  • High availability for instant access to files when needed.
  • Resiliency and redundancy to ensure data integrity, even in the face of unexpected disruptions.

These capabilities have been critical for clients like professional sports teams, broadcasters, and creative agencies that manage vast libraries of high-value media content.

Comprehensive support and maintenance

CHESA’s dedicated support services and Backblaze’s reliable cloud infrastructure ensure organizations experience minimal downtime and sustained operational efficiency. This comprehensive support includes:

  • Proactive monitoring and maintenance.
  • Remote and onsite assistance for hardware, software, and workflows.
  • Consistent communication to address issues before they impact production.

Why this partnership matters

The expanded Backblaze and CHESA partnership is more than just a collaboration—it’s a commitment to empowering media organizations with innovative, efficient, and secure solutions. Here’s why it stands out:

  • Deeply customized solutions: Every organization’s needs are unique. Backblaze Solution Engineers and CHESA Workflow Engineers dive deep into clients’ specific workflows and objectives to design and implement solutions specifically tailored to their needs.
  • Unrivaled expertise, built over decades: Rely on the combined power of Backblaze and CHESA’s deep-rooted experience in cloud storage and media technology.
  • Your future-proof media strategy: Navigate the changing media landscape with confidence, leveraging our scalable and cutting-edge solutions.

Take the next step

Whether you’re a professional sports team looking to enhance fan engagement, a broadcaster aiming to streamline production, or a creative agency seeking cost-effective storage, Backblaze and CHESA are here to help.

Discover how our expanded solutions can revolutionize your media workflows. Visit our dedicated solution page to learn more and to schedule a consultation tailored to your organization’s needs.

Learn More about Backblaze + CHESA  ➔ 

The post Backblaze and CHESA: Doubling Down on a Premier Media Workflow Partnership appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

A Playbook for Migrating Your Media to a MAM System

Post Syndicated from Laquie TN Campbell original https://www.backblaze.com/blog/workflow-playbook-migrating-your-media-assets-to-a-mam/

A decorative image showing media icons over a cloud with the title "Easily Access Your Organized Media Assets."

Media asset management systems (MAM) have become a standard tool in the tech stack of many media organizations. MAM systems have evolved from basic file storage to sophisticated platforms with advanced organization features, increasing efficiency, collaboration, and distribution speeds. 

In this post, I’ll explain some media asset management basics and introduce five key plays you can put into practice to get the most out of your assets, including how to move them into a MAM system or migrate from an older system to a new one.

Why do you need a MAM system?

As a media professional, I’ve come across some, let’s say, creative file naming conventions in my day. While it’s hilarious, “Episode6-Final-final-v2.3_OH_YEAH_THIS_IS_DEFINITELY_THE_FINAL_ONE_2_LOL.mp4” isn’t going to be the easiest thing to find years later when you’re searching through hundreds of files for the (for real) final one.

Whether you make videos, images, or music, the more you produce, the more difficult those assets become to manage, organize, find, and protect. Managing files by carefully placing them in specific folders and implementing more logical naming conventions can only get you so far. At some point, as the scale of your business grows, you’ll find your current way of organizing and searching for assets can’t keep up. That’s where media asset management systems come in.

MAM systems explained: Key concepts

Before you start building a playbook to get the most from your creative assets, let’s review a few key concepts.

Assets and metadata

Asset: A rich media file with intrinsic metadata.

An asset is simply a file that is the result of your creative operation. Most often, it is a rich media file like an image or a video. Typically, these files are captured or created in a raw state, then your creative team adds value to that raw asset by editing it and creating a finished story that in turn, becomes another asset to manage.

Metadata: Information about a file, either embedded within the file itself or associated with the file by another system, typically a MAM application.

Any given file carries information about itself that can be understood by your laptop or workstation’s operating system. Some of these seem obvious, like the name of the file, how much storage space it occupies, when it was first created, and when it was last modified. These would all be helpful ways to try to find one particular file you are looking for among thousands just using the tools available in your OS’s file manager.

File metadata: Information about a file specifically pertaining to the technical attributes of the file. 

There’s usually another level of metadata embedded in media files that is not so obvious but potentially enormously useful: Metadata embedded in the file when it’s created by a camera, film scanner, or output by a program.

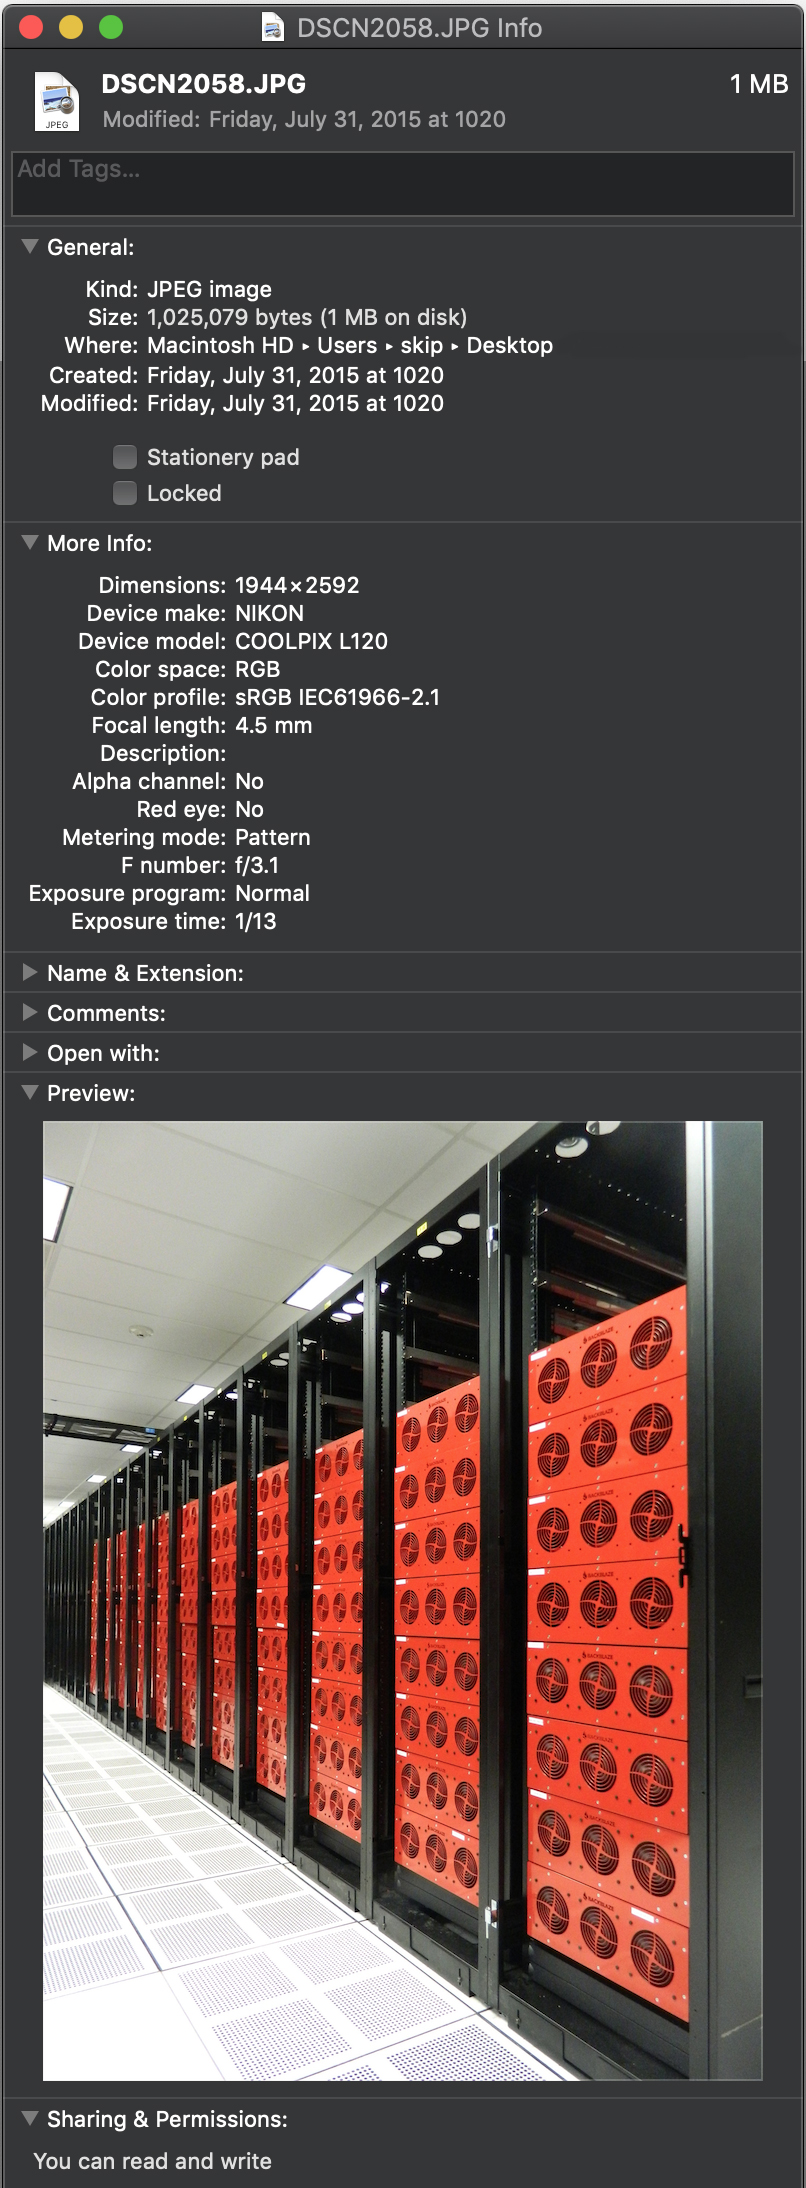
Results of a file inspected by an operating system's file manager
An example of metadata embedded in a rich media file.

For example, this image taken in Backblaze’s data center carries all kinds of interesting information. When I inspect the file, I can see a wealth of information. I now know the image’s dimensions and when the image was taken, as well as exactly what kind of camera took this picture and the lens settings that were used.

As you can see, this metadata could be very useful if you want to find all images taken on that day, or even images taken with that same camera, focal length, F-stop, or exposure.

Going through files one at a time to find the one you need is incredibly inefficient. Yet that’s how things still work in many creative environments—an ad hoc system of folders plus the memory of whoever’s been with the team longest. Files are often kept on the same storage used for production or even on an external hard drive.

Teams quickly outgrow that system when they find themselves juggling multiple hard drives or they run out of space on production storage. Worst of all, assets kept on a single hard drive are vulnerable to disk damage or to being accidentally copied or overwritten. Even if standard protocol is a redundant backup process, natural disasters can become a serious threat depending on the location of the physical tapes or drives.

Why your assets need to be managed

To meet this challenge, creative teams have often turned to MAMs. A MAM automatically extracts all of the assets’ inherent metadata, helps move files to protected storage, and makes them instantly available to MAM users. As time has gone on, we’ve seen MAM systems be powerfully enhanced by AI. In a way, these MAMs become a private media search engine where any file attribute can be a search query to instantly uncover the needed files in even the largest media asset libraries.

Beyond that, asset management systems are rapidly becoming highly effective collaboration and workflow tools. For example, tagging a series of files as Field Interviews — April 2019, or flagging an edited piece of content as HOLD — do not show customer can be very useful indeed.

Inner workings of a media asset manager

When you add files into an asset management system, the application inspects each file, extracting every available bit of information about the file, noting the file’s location on storage, and often creating a proxy version of the file that is easier to present to users.

To keep track of this information, asset manager applications employ a database and keep information about your files in it. This way, when you’re searching for a particular set of files among your entire asset library, you can simply make a query of your asset manager’s database in an instant rather than rifling through your entire asset library storage system. The application takes the results of that database query and retrieves the files you need.

A MAM Case Study: Complex Networks

Complex Networks was running out of space. Whenever local shared storage filled up, they had to pull assets off to give everybody enough room to continue working. They moved all of their assets to iconik media asset management software and backed them all up to the Backblaze B2 Cloud Storage. They’re now free to focus on what they do best—making culture-defining content—rather than spending time searching for assets.

Read the Full Story ➔ 

Asset migration playbook

Whether you need to move from a file and folder based system to a new asset manager, or have been using an older system and want to move to a new one without losing all of the metadata that you have painstakingly developed, a sound playbook for migrating your assets can help guide you. Below we’ll explain five plays you can use to approach your asset management journey:

Play 1: Protecting assets saved in a folder hierarchy without an asset management system

In this scenario, your assets are in a set of files and folders, and you aren’t ready to implement your asset management system yet.

The first consideration is for the safety of the assets—backup and archive. Files on a single hard drive are vulnerable, so if you are not ready to choose an asset manager your first priority should be to get those files into a secure cloud storage service like Backblaze B2.

Then, when you have chosen an asset management system, you can simply point the system at your cloud-based asset storage to extract the metadata out of the files and populate the asset information in your asset manager.

How to run it:

  1. Get assets archived or moved to cloud storage.
  2. Choose your asset management system.
  3. Ingest assets directly from your cloud storage.

Play 2: Moving assets saved in a folder hierarchy into your asset management system and archiving in cloud storage

In this scenario, you’ve chosen your asset management system, and need to get your local assets in files and folders ingested and protected in the most efficient way possible.

You’ll ingest all of your files into your asset manager from local storage, then back them up to cloud storage. Once your asset manager has been configured with your cloud storage credentials, it can automatically move a copy of local files to the cloud for you. Later, when you have confirmed that the file has been copied to the cloud, you can safely delete the local copy.

How to run it:

  1. Ingest assets from local storage directly into your asset manager system.
  2. From within your asset manager system archive a copy of files to your cloud storage.
  3. Once safely archived, the local copy can be deleted.

Play 3: Getting a lot of assets on local storage into your asset management system and backing up to cloud storage

If you have a lot of content, more than say, 20TB, you will want to use a rapid ingest service similar to the Backblaze Fireball system. You copy the files to the Backblaze Fireball, Backblaze puts them directly into your asset management bucket, and the asset manager is then updated with the file’s new location in your Backblaze B2 account.

This can be a manual process, or can be done with scripting to make the process faster.

How to run it:

  1. Ingest assets from local storage directly into your asset manager system.
  2. Archive your local assets to Fireball (up to 90TB at a time).
  3. Once the files have been uploaded by Backblaze, relink the new location of the cloud copy in your asset management system.

Play 4: Moving from one asset manager system to another without losing metadata

In this scenario you have an existing asset management system and need to move to a new one as efficiently as possible. You want to take advantage of your new system’s features and safeguard in cloud storage in a way that does not impact your existing production.

Some asset management systems will allow you to export the database contents in a format that can be imported by a new system. Some older systems may not have that feature and will require the expertise of a database expert to manually extract the metadata. Either way, you can expect to need to map the fields from the old system to the fields in the new system.

Making a copy of your old database is a must. Don’t work on the primary copy, and be sure to conduct tests on small groups of files as you’re migrating from the older system to the new. You need to ensure that the metadata is correct in the new system, with special attention that the actual file location is mapped properly. It’s wise to keep the old system up and running for a while before completely phasing it out.

How to run it:

  1. Export the database from the old system.
  2. Import the records into the new system.
  3. Ensure that the metadata is correct in the new system and file locations are working properly.
  4. Make archive copies of your files to cloud storage.
  5. Once the new system has been running through a few production cycles, it’s safe to power down the old system.

Play 5: Moving quickly from a MAM on local storage to a cloud-based system

In this variation of Play 4, you can move content to object storage with a rapid ingest service like Backblaze Fireball at the same time that you migrate to a cloud-based system. This step will benefit from scripting to create records in your new system with all of your metadata, then relink with the actual file location in your cloud storage all in one pass.

You should test that your asset management system can recognize a file already in the system without creating a duplicate copy of the file. This is done differently by each asset management system.

How to run it:

  1. Export the database from the old system.
  2. Import the records into the new system while creating placeholder records with the metadata only.
  3. Archive your local assets to the Backblaze Fireball (up to 90TB at a time).
  4. Once the files have been uploaded by Backblaze, relink the cloud based location to the asset record.

Bonus play: Using cloud storage to scale a media heavy workload

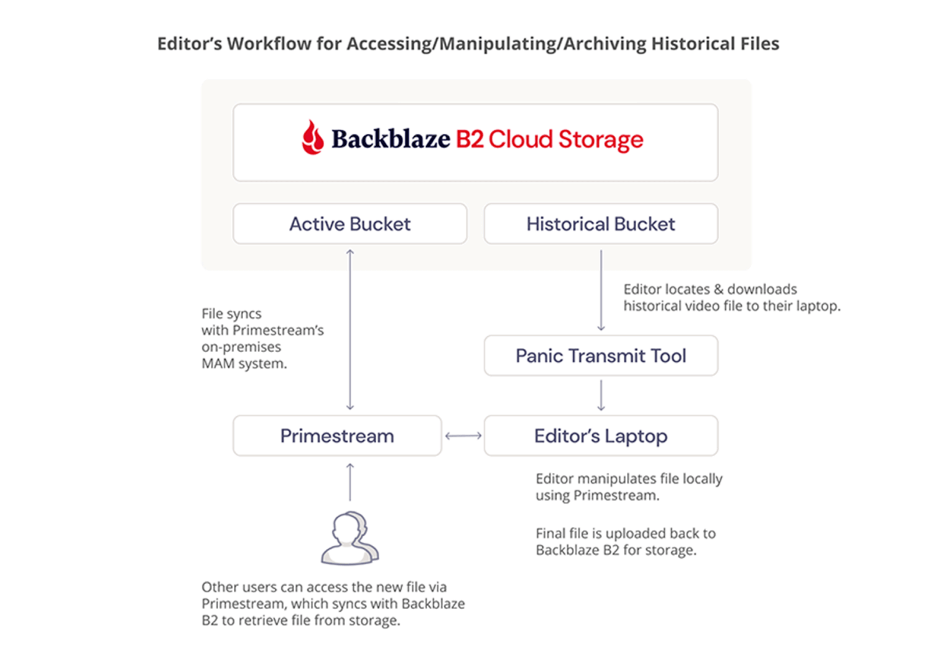
Fortune Media’s tech stack was expensive, difficult to use, and not 100% reliable. They migrated over 300TB of data, mainly video files, to Backblaze B2 Cloud Storage, which integrated with their preferred MAM system, Primestream Xchange, removing the need for archiving middleware and simplifying the tech stack.

Wrapping up

Every creative environment is different, but all need the same thing: to be able to find assets fast and organize content to enhance productivity and rest easy knowing that content is safe.

With these plays, you can take that step and be ready for any future production challenges and opportunities.

The post A Playbook for Migrating Your Media to a MAM System appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

The Philadelphia Eagles Make Real-Time Content Production a Reality

Post Syndicated from Laquie Campbell original https://www.backblaze.com/blog/how-to-migrate-mam-to-cloud/

A decorative image showing a football helmet with the Backblaze logo.

Media and entertainment professionals have long debated how and where cloud services best fit in their workflows. Archive was initially seen as the most natural fit. But end-to-end cloud workflows and cloud-based production were viewed with skepticism due to the network bandwidth required to edit full resolution content. Now, as more organizations lean into REMI workflows, and new cloud-oriented creative tools enable real-time content production, the cloud is playing a role at every step of creative workflows.

Of course, it’s one thing to talk about real-time production in the cloud and it’s another thing to show how the cloud has transformed an actual workflow from end-to-end. But that’s exactly what the Philadelphia Eagles media team did by building a streamlined work-from-anywhere solution with cloud storage and cloud-delivered asset management. The best part was that rolling out the new cloud workflow was just as painless as it was transformative for their business.

We went from frequent LTO crashes and long restore times to near-instant access for every stored clip.

—Stacy Kelleher, Director of Production, Philadelphia Eagles

Archive availability sidelines production efforts

The Eagles were using a portfolio of different storage systems to store petabytes of content with different availability for each tier. The best they could hope for when restoring clips from LTO, for example, was half real-time. So, a three hour clip might take an hour and half to restore—and that’s if the LTO system was working at all. It became so problematic that they stopped archiving content to LTO altogether, opting to max out their SAN to ensure fast access.

The desire for faster file-sharing led the business requirements for overhauling their storage infrastructure. They needed to:

  • Consolidate their storage infrastructure.
  • Improve remote access faster for sharing content internally or even monetizing it outside the organization. 
  • Improve the reliability of their backup and archive solution.

But migrating data and setting up a new system is no small feat.

Migration can’t run down the clock

Anyone who’s ever done a legacy migration knows moving to a new system is a quagmire. You can’t tell IT: You need to stop syncs and backups for three weeks while we do a migration.

—Ryan Lakey, Principal Lead, Solutions, CHESA

There’s a reason folks in the media and entertainment space dread a migration. It’s slow. It’s semi-painful. And, everything has to port over correctly. 

The Eagles approached their migration in the off season. They needed some flexibility to consolidate their multiple SANs, stadium production operations, and LTO system into something that helped them fly higher. 

They consolidated the data into one single tier with a Quantum QSX on site for nearline storage and shifted hundreds of terabytes from their SAN and LTO system to Backblaze as their off-site storage for backup and archive. 

Cloud MAM for the win

With storage sorted, the Eagles then integrated Mimir, a video collaboration and production platform that includes production asset management, archive, and object-store integration, to keep everything organized and on time. Whenever a file is uploaded to Mimir, it’s automatically stored in Backblaze B2 via Mimir’s file indexer system Kelda. This covered the game day action—their production team had fast access to recently recorded content, providing flexibility to work from home after those late night games. 

Getting our sponsored, highest-performing content out quickly drives more views and boosts revenue, so efficiency on game day is critical. Our newly streamlined workflows ensure our editors can deliver while the content is still relevant and engaging.

—Stacy Kelleher, Director of Production, Philadelphia Eagles

The final score

The new system empowers their production team by giving them instant access and fast workflows so they can work without slowdowns. Kelleher noted that restoring a clip is nearly instant. 

They have the ability to share links directly from Mimir to users outside the organization for things like pre-season broadcasts, which comes in handy especially when those users don’t want, need, or have the equipment to download the entire broadcast file. Stacy can just copy and paste a Mimir link into an email, and outside agencies or users can watch entire games at speed. 

Finally, they freed up IT staff time spent managing all that tape and old hardware, not to mention physical space. It all added up to a big win for the IT team, the franchise, and the fans.

Now I can easily share entire broadcasts by copying and sharing a link from our MAM. No need for FTP downloads or uploading to other platforms. It’s fast, seamless, and ensures everyone can view the content without issues.

—Stacy Kelleher, Director of Production, Philadelphia Eagles

The post The Philadelphia Eagles Make Real-Time Content Production a Reality appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

5 Ways to Use Event Notifications to Advance Your Media Better, Faster

Post Syndicated from Jeremy Milk original https://www.backblaze.com/blog/5-ways-to-use-event-notifications-to-advance-your-media-better-faster/

A decorative image showing a cloud with digital lines and media icons.

In the hurry-up-and-wait world of media production, anything you can do to speed through the hurry-ups and avoid or shorten the waits is not just a gift—it’s an advantage that can mean happier team members, delighted clients and fans, and more revenue.

Backblaze Event Notifications can help.This new B2 Cloud Storage feature can help you streamline a range of your production tasks—like automatically starting transcoding of video and distributing new images—across your preferred workflow tools. 

Today, I’m sharing five ways you can use Backblaze Event Notifications to operationalize media production efficiencies. If you’re interested in Event Notifications for applications, check out this post; and stay tuned for a future post on how to use Event Notifications for IT backup.

Event Notifications for media production: Simplified automation

Event Notifications monitors your B2 Cloud Storage for data changes that you designate—think raw video uploads, content version updates, deletions, etc.—and delivers near real-time alerts where you want them about these changes. These alerts can be used to create awareness faster, and even more powerfully, to initiate streamlined end-to-end processes that can save you time and hassle, and avoid unnecessary manual tasks and/or the cost of complex intermediaries.

What are webhooks?

Webhooks, if you’re not familiar with the term, are HTTP-based callback functions that enable event-based communications between software applications. Backblaze Event Notifications can uniquely work with any external service that accepts webhooks. This means you can use it to your advantage across your media production workflow—and this is novel when most vendors’ alerts features are limited to closed ecosystems or require significant and sometimes costly workarounds to communicate beyond a limited set of production tools.

Top 5 use cases for media production

Here are specific, practical ways people producing and managing media can take advantage of Event Notifications for immediate benefits.

1. New content processing

Event Notifications can be used to trigger tasks immediately after new content is uploaded. Imagine one of your team members uploads a video or image: Event Notifications can be sent to a transcoding service to format it and a tagging service to categorize it for better content organization. Set up to furthermore extract valuable metadata too—all in near real time, without manual intervention. 

General workflow (abbreviated)

By automating these processes, companies can ensure that user-generated content is formatted correctly, appropriately tagged, and moderated without delay. This not only saves time but guarantees a consistent user experience.

What’s more, you can even go full Jedi Knight and handle errors programmatically with Event Notifications logic that triggers reprocessing tasks whenever issues arise.

2. Integrated alerts in go-to tools

Event Notifications can easily integrate with your communication tools like Slack and productivity tools like Zapier, to inform internal and external stakeholders of updates without them needing to check for them manually. Users have told us this is a great way to keep people updated when assets are added, updated, or advanced to key stages in production and post cycles—setting them up to consider taking downstream actions that don’t lend themselves to further process automation.

Asset change announcement workflow

Additionally, for teams using workflow tools such as Zapier to connect various services, Event Notifications makes it simple to trigger actions across multiple platforms, enabling powerful, automated workflows with your data in B2 Cloud Storage.

3. Over-the-top (OTT) streaming automation

Regardless of whether your streaming model is AVOD, TVOD, or SVOD, Event Notifications can help automate processing and distribution workflows. Users can enable them so that every time a new title is added to B2 Cloud Storage, it then triggers alerts that initiate transcoding, compression, and prep for delivery or playback via content delivery network (CDN).

OTT streaming platform workflow

4. Backup completion monitoring

An important (if unglamorous) aspect of managing media is backing it up for extra safekeeping. After all, it’s a precious asset worth a lot of money now and later. So whether you back up nightly, monthly, at project’s end, or on some other cadence, with Event Notifications, customers can set up to receive updates when their media backups are successfully uploaded to a Backblaze B2 Bucket—providing peace of mind when data is protected.

We’ve also had a few users already tell us that not seeing backup completion alerts when expected helped them realize that they had other, previously unknown workflow hiccups to address.

Backup complete workflow

Tangentially related, media organizations are also using Backblaze Cloud Replication to programmatically store their content to two or more geographically distributed locations for added protection—this isn’t the same as Event Notifications, but is another automation tool for enhancing your protection posture.

5. Monitor data usage

Since Event Notifications messages are sent within seconds of files being uploaded and deleted, and they contain the size of the file in question, you can easily and reliably track your data usage in near real time, helping you identify trends and potential issues. For example, if you know large raw files are coming in and then messages indicating much smaller than expected file sizes were uploaded, it can alert you to begin to QC it.

We’ve also seen such data monitoring prove highly beneficial to IT personnel who support them because the near real-time monitoring allows faster responses to situations as they are happening, thereby mitigating risks, reducing costs, and/or nipping issues in the bud so the production teams remain disruption and distraction free.

Monitoring workflow

Beyond these example use cases, Event Notifications opens up a wide range of possibilities for automating and optimizing workflows. This flexibility makes it easy to automate how your infrastructure interacts with and reacts to file changes in B2 Cloud Storage, simplifying workflows across your distributed services. So go ahead and get creative—and please do share with us the cool things you’re doing with Event Notifications.

Why Event Notifications matter for production workflows

The benefits of real-time notifications extend beyond simply saving time—they transform the way teams work, automate processes, and reduce the margin for error.

  • Awareness: Instant notifications for uploads, updates, or deletions keep everyone on the same page.
  • Actionable insights: Real-time alerts provide critical information that helps make informed decisions quickly.
  • Flexibility: Direct connections to services like media asset managers (MAMs), transcoding applications, and CDNs mean more choice to stick with your preferred stack and less lock-in to specific vendors or tools.
  • Cost efficiency: Automating tasks like media transcoding, data processing, or content delivery reduces the need for manual labor, saving on operational costs and freeing up resources for other strategic initiatives.

Improved security: By instantly alerting teams to changes or unusual activity, Event Notifications help maintain data integrity and support proactive security measures.

How Event Notifications compares

Unlike other offerings like Amazon’s messaging services, which are limited to specific ecosystems, Backblaze Event Notifications integrates directly with any service that accepts webhooks, offering true flexibility and avoiding vendor lock-in.

Event Notifications is also designed for at-least-once delivery, ensuring critical notifications are not missed. This reliability is important for teams building workflows that require precision and a level of consistency their end users expect. 

The pricing for Event Notifications is simple and transparent. Backblaze B2 Reserve customers enjoy unlimited free Event Notifications, while pay-as-you-go Backblaze B2 customers enjoy 2,500 calls per day free and then $0.004 per 10,000 transactions. This straightforward pricing applies no matter the service receiving the notification. This enables businesses to confidently scale their event-driven workflows, knowing exactly what to expect in terms of costs, regardless of the services they choose to integrate with. 

Ready to add automation to your media tasks?

For existing customers working with a Backblaze account manager, Event Notifications is already enabled for you, and your account manager can assist with any questions. If you’re an existing customer not currently working with an account manager, please contact our Support team to request access to Event Notifications. 

New customers can contact our Sales team to learn more about how Event Notifications can streamline workflows and how to get started.

Once Event Notifications are enabled, log in to your Backblaze B2 account, navigate to the Buckets page, and click on the Event Notifications section. From there, you can set up notification rules for the events you want to track or configure notifications using our API.

For detailed instructions and best practices, visit our Event Notifications documentation.

The post 5 Ways to Use Event Notifications to Advance Your Media Better, Faster appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

The Cloud Storage Playbook: 4 Best Practices for Sports Teams

Post Syndicated from Laquie Campbell original https://www.backblaze.com/blog/the-cloud-storage-playbook-4-best-practices-for-sports-teams/

A decorative image showing a cloud icon surrounded by media icons.

Video and data are the lifeblood of sports teams and leagues, fueling everything from fan engagement to game analysis. 

To keep operations running smoothly, sports teams need to ensure that assets are stored securely, managed cost effectively, and kept ready for quick access. Cloud storage is increasingly part of sports teams’ data management playbooks, integrating with existing workflows and media tools so that teams can stay sharp and keep fans engaged. 

Let’s break down what’s driving data growth in the sports market, use cases for cloud storage, and four best practices you can use to adopt cloud storage in a hybrid approach.

What’s driving data growth for sports teams?

During a given game, teams typically capture multiple camera angles, including sideline and aerial views, along with player-specific footage. Inside the stadium, teams use video and data to create an immersive fan experience, with big-screen displays and other screens showing player profiles, replays, real-time stats, and more. The action doesn’t stop there. Live feeds and exclusive content delivered on mobile devices add interactivity, bringing the game closer to the audience. 

Sports teams generate a massive amount of video and image data during a game. As an example, a given professional sports game may involve around 10–12 cameras, and each can generate several terabytes of high-definition (high-def) footage over the course of the game.

High-def video files can range from 1–3GB per minute of footage, meaning a two to three hour game with multiple cameras might produce dozens of terabytes. On top of that, teams use high speed cameras for slow motion analysis, which further increases the data volume. When considering still images from different angles and high-resolution (hi-res) formats, the overall image and video data generated per game can easily reach 10–20TB or more, depending on the resolution and frame rates used.

How sports organizations take advantage of cloud storage: Key use cases

Given the massive data growth in sports organizations, many teams rely on cloud storage to help them store, manage, and use that data effectively. Here’s how they do it.

Replacing aging on-premises systems

Professional sports teams have long relied on on-premises storage like LTO tape systems or servers to keep their game footage, player performance data, and other critical content safe. But as time goes on, these systems become harder to maintain, prone to breakdowns, and outmatched by the growing volume of data. As media and data continue to pile up, teams need storage that can scale fast without requiring a major investment in new infrastructure.

By using cloud storage—typically through a hybrid infrastructure that utilizes both cloud and on-premises systems—sports organizations can off-load some of the hassle of maintaining and upgrading aging physical systems. Cloud storage eliminates the need for constant hardware replacements, freeing up IT teams to focus on more strategic plays.

Eagles retire LTO, drafting up an active cloud archive

With multiple championships behind them, the Philadelphia Eagles had decades of incredible content to mine and protect, but they needed to draft and train up some new technical assets to stay in contention. They retired their LTO-6 system and shifted hundreds of terabytes off of their storage area network (SAN) to a true cloud archive in Backblaze B2 Cloud Storage. Check out their game plan for protecting data and improving media workflows in the cloud.

Enhancing video management and distribution

By implementing cloud storage for hot archives, a league or team can store all video content in a centralized repository that offers instant access from anywhere, especially when paired with cloud-friendly media asset management (MAM) tools. 

Cloud storage simplifies the process of sharing large video files with players, broadcasters, and media outlets, boosting an organization’s ability to monetize its content. 

Backblaze B2 Live Read changes the game

Advanced services like Live Read give teams the ability to access, edit, and transform media as it’s uploaded. This speeds up content retrieval for analysis, editing, and distribution, making it especially useful on game days, when quick access to video and analytics can influence real-time decisions and help create up-to-the-minute content.

Business continuity and disaster recovery

Keeping sensitive data and high value media safe is nonnegotiable for sports organizations. A natural disaster, cyberattack, data breach, or other threat to stored data and media can cause days or weeks of downtime, making critical assets inaccessible and leading to significant operational disruptions. 

Teams are using cloud storage to create geographic redundancy that ensures that data stays secure and recoverable even in the event of a local disaster. Tools like Object Lock add an extra layer of protection, making sure that data can’t be tampered with or deleted.

Integrating AI capabilities

AI is employed by sports teams to automate video analysis and content tagging, create highlight reels almost instantly, and scale personalization efforts. 

Using the cloud to implement AI for sports media makes sense thanks to its scalability, processing power, and accessibility. Cloud platforms can handle vast amounts of video data and provide the computational resources necessary for AI-driven tasks like real-time analysis, high-speed editing, and video rendering. The cloud also enables collaboration across multiple locations, allowing teams, coaches, and analysts to access and process data seamlessly. Cloud-based AI is cost efficient, as teams only pay for the resources they use, avoiding the high costs of maintaining dedicated on-premises AI infrastructure.

Leverage video understanding with Twelve Labs

Twelve Labs’ video understanding platform allows you to build AI functionality into your workflows, giving you the ability to automate metadata tagging and search video archives with natural language. Check out how it integrates with cloud storage in Backblaze B2.

Optimizing costs

As traditional storage systems scale up, they can become prohibitively expensive—not only in direct costs, but also in ongoing maintenance and management. Cloud storage is inherently scalable, capable of handling growing volumes of content and data without breaking the bank. 

Cloud storage helps sports teams optimize data storage costs by offering scalable, flexible pricing models that align with their data needs. Depending on their needs, teams can choose to pay for the exact amount of storage they use or to leverage capacity-based storage plans, but in either case, they’ll avoid the need for expensive on-premises hardware that often requires over-provisioning. 

With cloud storage, teams can dynamically scale storage up or down based on their requirements—like during the season when video data surges—though it’s essential to consider things like egress fees in cost calculations. Backblaze, for example, includes 3x free egress, which can reduce costs significantly

Hybrid cloud storage for sports teams

Many organizations take a phased approach in embracing cloud storage, or choose to continue leveraging on-premises storage infrastructure along with new cloud storage resources in a hybrid model. As with any deployment of new technology, this process is best undertaken with a thoughtful game plan.

Four best practices for adopting hybrid cloud storage

1. Assess your current infrastructure

Begin by auditing the on-premises storage systems you currently rely on to maintain team footage and data. Knowing where your storage infrastructure falls short, you can set clear objectives for a hybrid solution, such as increased accessibility or more cost-effective scaling options, and then map out your shift to the cloud. Evaluate capacity, performance, and scalability limits to help identify pain points (e.g., slow access to media files, high costs) and inform prioritization of the data or content that should move to the cloud. 

2. Prioritize media for migration

Depending on your goals, you’ll prioritize different media for a cloud migration. For example, if your goal is to modernize your archive and make it more accessible for monetization, it makes sense to move archives off LTO to an active cloud archive. On the other hand, if your goal is streamlining remote workflows, your production data is likely first up for a cloud migration while you can maintain on-premises solutions for your archives as long as they’re serving your needs. 

3. Leverage hybrid storage as a transition stage

With a cloud storage platform that integrates smoothly with existing on-prem storage and applications, you are well positioned to implement a hybrid cloud solution. A hybrid storage model allows you to shift operations to the cloud gradually, without the need for an abrupt overhaul. As you navigate this transition, your team can begin to take advantage of cloud scalability and flexibility without abandoning familiar workflows or compromising performance.

4. Establish clear data management policies

Structured data management helps prevent inefficiencies, such as duplicated or misplaced files, and ensures that storage solutions align with operational needs. Create clear policies for where media and data are stored (on-prem or cloud), when and how each should be moved, and which users have access (and at what level).

Preparing for the future

As sports organizations continue to generate and rely on massive amounts of video and data, cloud storage is increasingly becoming a strategic necessity. By embracing cloud storage, teams and leagues can increase their efficiency, improve fan engagement, enhance performance analysis, and ensure operational continuity—all while optimizing costs and future-proofing their infrastructure. The result? More streamlined, secure, and scalable storage that supports long-term success on and off the field.

The post The Cloud Storage Playbook: 4 Best Practices for Sports Teams appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

Backblaze Live Read: The Game Changer for Live Media Cloud Workflows

Post Syndicated from Elton Carneiro original https://backblaze.com/blog/announcing-b2-live-read/

A decorative image with the title Live Read.

Every sports fan knows that when something incredible happens on the field/ice/court, we want to see the replay right now. But many of us don’t know the impressive efforts that live media teams undertake to deliver clips in real time to all of us on whatever viewing platform we might prefer. Today, Backblaze is excited to make the work of live media production (and the end results) a lot easier with our latest innovation.

Announcing Backblaze B2 Live Read

Backblaze B2 Live Read is a patent-pending service that gives media production teams working on live events the ability to access, edit, and transform media content while it is being uploaded into Backblaze B2 Cloud Storage. This means that teams can start working on content far faster than they could before, without having to drastically change their workflows and tools, massively speeding up their time to engagement and revenue. 

This is a game changer for live media teams, who are passionate about bringing content to their audience as soon as possible. It means they don’t need to worry as screen resolutions continue to expand, ranging from 4K to 8K and beyond. It also reduces the need for having production teams on-site to minimize latency, which could be extremely costly depending on the venue. 

Previously, producers had to wait hours or days before they could access uploaded data, or they had to rely on cost-prohibitive and complicated options that often required on-premises storage. That’s no longer necessary. This innovation will make it faster and less expensive to:

  • Create near real-time highlight clips for news segments, in-app replays, and much more.
  • Tap into talent where they are versus trying to find local talent to produce events.
  • Promote content for on-demand sales within minutes of presentations at live events.
  • Distribute teasers for buzz on social media before talent has even left the venue.

For our customers, turnaround time is essential, and Live Read promises to speed up workflows and operations for producers across the industry. We’re incredibly excited to offer this innovative feature to boost performance and accelerate our customers’ business engagements.”

Richard Andes, VP, Product Management, Telestream

Coming soon inside your favorite tools

We designed Live Read to be easily accessible directly via the Backblaze S3 Compatible API and/or seamlessly within the user interface of launch partners including Telestream, Glookast, and Mimir. These platforms, along with CineDeck, Alteon, Hedge, Hiscale, MoovIT, and many others to come, are enabling Live Read within their platforms soon.   

If you want to use Live Read, you can join our private preview.  

How does it work?

Previously, media teams were forced to either wait for uploads to complete or use on-premises storage. Now, Live Read uniquely supports accessing parts of each growing file or growing object as it is uploaded so there’s no need to wait for the full file upload to complete. And, when the full upload is complete, it’s accessible like any other file in a Backblaze B2 Cloud Storage Bucket, with no middleware or proprietary software needed. 

Here’s a short video showing both how Live Read works on a conceptual level, as well as a live demo showing how one app can upload video data to Backblaze B2 using Live Read while a second app reads the uploaded video data:

For those of you who want to dig deeper into the code samples you saw in the video, here is some example code that uses the Amazon SDK for Python, Boto3, to start uploading data with Live Read. If you’re familiar with Amazon S3, you’ll recognize that this is a standard multipart upload apart from the add_custom_header handler function and the call to register it with Boto3’s event system:

def add_custom_header(params, **_kwargs):
    """
    Add the Live Read custom headers to the outgoing request.
    See https://boto3.amazonaws.com/v1/documentation/api/latest/guide/events.html
    """
    params['headers']['x-backblaze-live-read-enabled'] = 'true'

client = boto3.client('s3')
client.meta.events.register('before-call.s3.CreateMultipartUpload', add_custom_header)

response = client.create_multipart_upload(Bucket='my-video-files', Key='liveread.mp4')

upload_id = response['UploadId']

# Now upload data as usual with repeated calls to client.upload_part()

As it processes the call to create_multipart_upload(), Boto3 calls the add_custom_header() handler function, which adds a custom HTTP header, x-backblaze-live-read-enabled, with the value true, to the S3 API request. The custom HTTP header signals to Backblaze B2 that this is a Live Read upload. As with standard multipart uploads, the data is uploaded in parts between 5MB and 5GB in size. To facilitate reading data efficiently, all parts except the last one must have the same size.

Since this is a Live Read upload, as soon as a part is uploaded, it is accessible for downloading.

An app that downloads the file needs to send the same custom HTTP header when it retrieves data. For example:

def add_custom_header(params, **_kwargs):
    """
    Add the Live Read custom headers to the outgoing request.
    See https://boto3.amazonaws.com/v1/documentation/api/latest/guide/events.html
    """
    params['headers']['x-backblaze-live-read-enabled'] = 'true'

client = boto3.client('s3')
client.meta.events.register('before-call.s3.GetObject', add_custom_header)

# Read the first 1 KiB of the file
response = client.get_object(
    Bucket='my-video-files',
    Key='liveread.mp4',
    Range='bytes=0-1023'
)

Note that you must supply either Range or PartNumber to specify a portion of the file when you download data using Live Read. If you request a range or part that does not exist, then Backblaze B2 responds with a 416 Range Not Satisfiable error, just as you might expect. On receiving this error, an app reading the file might repeatedly retry the request, waiting for a short interval after each unsuccessful request.

The source code for the applications is available as open source at https://github.com/backblaze-b2-samples/live-read-demo/.

How much does it cost?

Live Read upload capacity is offered in $15/TB increments—and the capacity is only consumed when an upload is marked for Live Read. Standard uploads are free, as usual. After uploading is complete, the data stored in Backblaze B2 is billed as normal. From a cost perspective, this represents significant savings versus the workflows that production teams must currently follow to achieve anything close to the functionality delivered by Live Read.

And it’s not just for live media

Beyond media, the Live Read API can support breakthroughs across development and IT workloads. For example, organizations maintaining large data logs or surveillance footage backups have often had to parse them into hundreds or thousands of small files each day in order to have quick access when needed—but with Live Read, they can now move to far more manageable single files per day or hour while preserving ability to access parts immediately after they are written.

What’s next

For those interested in Live Read, you can sign up for the private preview here. We’ll continue to report as we add more integrations and we’ll share stories as customers succeed with the new feature. Until then, feel free to ask any question you have in the comments below. 

Want to see more?

Join Pat Patterson, Chief Technical Evangelist, and Elton Carneiro, Senior Director of Partnerships, on January 26, 2024 at 10:00 a.m. PT to learn more in real time. Can’t make it live? Sign up anyway and we’ll send a recording straight to your inbox.

Join the Webinar 

The post Backblaze Live Read: The Game Changer for Live Media Cloud Workflows appeared first on Backblaze Blog | Cloud Storage & Cloud Backup

AI Video Understanding in Your Apps with Twelve Labs and Backblaze

Post Syndicated from Pat Patterson original https://backblaze.com/blog/ai-video-understanding-in-your-apps-with-twelve-labs-and-backblaze/

A decorative header depicting several screens with video editing tasks and a cloud with the Backblaze logo on it.

Over the past few years, since long before the recent large language model (LLM) revolution, we’ve benefited not only from the ability of AI models to transcribe audio to text, but also to automatically tag video files according to their content. Media asset management (MAM) software—such as Backlight iconik and Axle.ai (both Backblaze Partners, by the way)—allows media professionals to quickly locate footage by searching for combinations of tags. For example, “red car”, will return not only a list of video files containing red cars, but also the timecodes pinpointing the appearance of the red car in each clip.

San Francisco startup Twelve Labs has created a video understanding platform that allows any developer to build this kind of functionality, and more, into their app via a straightforward RESTful API. 

In preparation for our webinar with Twelve Labs last month, I created a web app to show how to integrate Twelve Labs with Backblaze B2 for storing video. The complete sample app is available as open source at GitHub; in this blog post, I’ll provide a brief description of the Twelve Labs platform, explain how presigned URLs allow temporary access to files in a private bucket, and then share the key elements of the sample app. If you just want a high level understanding of the integration, read on, and feel free to skip the technical details!

The Twelve Labs Video Understanding Platform

The core of the Twelve Labs platform is a foundation model that operates across the visual, audio, and text modes of video content, allowing multimodal video understanding. When you submit a video using the Twelve Labs Task API, the platform generates a compact numerical representation of the video content, termed an embedding, that identifies entities, actions, patterns, movements, objects, scenes, other elements of the video, and their interrelationships. The embedding contains everything the Twelve Labs platform needs to do its work—after the initial scan, the platform no longer needs access to the original video content. As each video is scanned into the platform, its embedding is added to an index, so this scanning process is often referred to as indexing.

As part of the indexing process, the platform extracts a standard set of data from each video: a thumbnail image, a transcript of any spoken content, any text that appears on screen, and a list of brand logos, all annotated with timecodes locating them on the video’s timeline, and all accessible via the Twelve Labs Index API.

You can have the platform create a title and summary, and even prompt the model to describe the video, via Twelve Labs’ Generate API. For example, I indexed an eight-minute video that explains how to back up a Synology NAS to Backblaze B2, then prompted the Generate API, “What are the two Synology applications mentioned in the video?” This was the first sentence of the resulting text:

The two Synology applications mentioned throughout the video are “Synology Hyper Backup” and “Synology Cloud Sync.”

The remainder of the response is a brief summary of the two applications and how they differ; here’s the full text. Although it does have that “AI flavor” as you read it, it’s clear and accurate. I must admit, I was quite impressed!

You can define a taxonomy for your videos via the Classify API. Submit a one- or two-level classification schema and a set of video IDs, and the platform will assign each video to a category.

Rounding up this quick tour of the Twelve Labs platform, the Search API, as its name suggests, allows you to search the indexed videos. As well as a search query, you must specify a set of content sources: any combination of visual, conversation, text in video, or logos. Each search result includes timecodes for its start and end.

Now you understand the basic capabilities of the Twelve Labs platform, let’s look at how you can integrate it with Backblaze B2.

Allowing Temporary Access to Files in a Private Backblaze B2 Bucket

A key feature of the sample app is that it uploads videos to a private Backblaze B2 Bucket, where they are only accessible to authorized users. Twelve Labs’ API allows you to submit a video for indexing by POSTing a JSON payload including the video’s URL to its Task API. This is straightforward for video files in a public bucket, but how do we allow the Twelve Labs platform to read files from a private bucket?

One way would be to create an application key with capabilities to read files from the private bucket and share it with the Twelve Labs platform. The main drawback to this approach is that the platform currently lacks the ability to sign requests for files from a private bucket.

Since Twelve Labs only needs to read the video file when we submit it for indexing, we can send it a presigned URL for the video file. As well as the usual Backblaze B2 endpoint, bucket name, and object key (path and filename), a presigned URL includes query parameters containing data such as the time when the URL was created, its validity period in seconds, an application key ID (or access key ID, in S3 terminology), and a signature created with the corresponding application key (secret access key). Here’s an example, with line breaks added for clarity:

https://s3.us-west-004.backblazeb2.com/mybucket/image.jpeg
?X-Amz-Algorithm=AWS4-HMAC-SHA256
&X-Amz-Credential=00415f935c00000000aa%2F20240423%2Fus-west-004%2Fs3%2Faws4_request
&X-Amz-Date=20240423T222652Z
&X-Amz-Expires=3600
&X-Amz-SignedHeaders=host
&X-Amz-Signature=23ade1...3ca1eb

This URL was created at 22:26:52 UTC on 04/23/2024, and was valid for one hour (3600 seconds). The signature is 64 hex characters. Changing any part of the URL, for example, the X-Amz-Date parameter, invalidates the signature, resulting in an HTTP 403 Forbidden error when you try to use it, with a corresponding message in the response payload:

<?xml version="1.0" encoding="UTF-8" standalone="yes"?>
<Error>
    <Code>SignatureDoesNotMatch</Code>
    <Message>Signature validation failed</Message>
</Error>

Attempting to use the presigned URL after it expires yields HTTP 401 Unauthorized with a message such as:

<?xml version="1.0" encoding="UTF-8" standalone="yes"?>
<Error>
    <Code>UnauthorizedAccess</Code>
    <Message>Request has expired given timestamp: '20240423T222652Z' and expiration: 3600</Message>
</Error>

You can create presigned URLs with any of the AWS SDKs or the AWS CLI. For example, with the CLI:

% aws s3 presign s3://mybucket/image.jpeg --expires-in 600 
https://s3.us-west-004.backblazeb2.com/mybucket/image.jpeg?X-Amz...

Presigned URLs are useful whenever you want to provide temporary access to a file in a private bucket without having to share an application key for a client app to sign the request itself. The sample app also uses them when rendering HTML web pages. For example, all of the thumbnail images are retrieved by the user’s browser via presigned URLs.

Note that presigned URLs are a feature of Backblaze B2’s S3 Compatible API. Creating a presigned URL is an offline operation and does not consume any API calls. We recommend you use presigned URLs rather than the b2_get_download_authorization B2 Native API operation, since the latter is a class C API call.

Inside the Backblaze B2 + Twelve Labs Media Asset Management Example

The sample app is written in Python, using JavaScript for its front end, the Django web framework for its backend, the Huey task queue for managing long-running tasks, and the Twelve Labs Python SDK to interact with the Twelve Labs platform. A simple web UI allows the user to upload videos to the private bucket, browse uploaded videos, submit them for indexing, view the resulting transcription, logos, etc., and search the indexed videos.

Most of the application code is concerned with rendering the web UI; very little code is required to interact with Twelve Labs.

Configuration

The Django settings.py file defines a constant for the Twelve Labs index ID and creates an SDK client object using the Twelve Labs API key. Note that the app reads the index ID and API key from environment variables, rather than including the values in the source code. Externalizing the index ID as an environment variable allows more flexibility in deployment while, of course, you should never include secrets such as passwords or API keys in source code!

TWELVE_LABS_INDEX_ID = os.environ['TWELVE_LABS_INDEX_ID']
TWELVE_LABS_CLIENT = TwelveLabs(api_key=os.environ['TWELVE_LABS_API_KEY'])

Startup

When the web application starts, it validates the index ID and API key by retrieving details of the index. This is the relevant code, in apps.py:

index = TWELVE_LABS_CLIENT.index.retrieve(TWELVE_LABS_INDEX_ID)

If this API call fails, then the app prints a suitable diagnostic message identifying the issue.

Indexing

When a web application needs to perform an action that takes more than a few seconds to complete—for example—indexing a set of videos, it typically starts a background task to do the work, and returns an appropriate response to the user. The sample app follows this pattern: when the user selects one or more videos and hits the Index button, the web app starts a Huey task, do_video_indexing(), passing the IDs of the selected videos, and returns the IDs to the JavaScript front end. The front end can then show that the indexing tasks have started, and poll for their current status.

Here’s the code, in tasks.py, for submitting the videos for indexing.

# Create a task for each video we want to index
for video_task in video_tasks:
    task = TWELVE_LABS_CLIENT.task.create(
        TWELVE_LABS_INDEX_ID,
        url=default_storage.url(video_task['video']),
        disable_video_stream=True
    )
    print(f'Created task: {task}')
    video_task['task_id'] = task.id

Notice the call to default_storage.url(). This function, implemented by the django-storages library, takes as its argument the path to the video file, returning the presigned URL. The default expiry period is one hour.

Once the videos have been submitted, do_video_indexing() polls for the status of each indexing task until all are complete. Most of the code is concerned with minimizing the number of calls to the API, and saving status to the app’s database; getting the status of a task is simple:

task = TWELVE_LABS_CLIENT.task.retrieve(video_task['task_id'])

The task object’s status attribute is a string with a value such as validating, indexing, or ready. When the task reaches the ready status, the task object also includes a video_id attribute, uniquely identifying the video within the Twelve Labs platform. At this point, do_video_indexing() calls a helper function that retrieves the thumbnail, transcript, text, and logos and stores them in Backblaze B2.

Retrieving Video Data

Here’s the call to retrieve the thumbnail:

thumbnail_url = TWELVE_LABS_CLIENT.index.video.thumbnail(TWELVE_LABS_INDEX_ID, video.video_id)

The helper function creates a path for the thumbnail file from the video ID and the file extension in the returned URL, and saves the thumbnail to Backblaze B2:

default_storage.save(thumbnail_path, urlopen(thumbnail_url))

Again, django-storages is doing the heavy lifting. We use urlopen(), from the urllib.request module, to open the thumbnail URL, providing default_storage.save() with a file-like object from which it can read the thumbnail data.

The calls to retrieve transcript, text, and logo data have a slightly different form, for example:

video_data = TWELVE_LABS_CLIENT.index.video.transcription(TWELVE_LABS_INDEX_ID, video.video_id)

Each call returns a list of VideoValue objects, each VideoValue object comprising a start and end timecode (in seconds) and a value specific to the type of data; for example, a fragment of the transcription. We serialize each list to JSON and save it as a file in Backblaze B2.

When the user navigates to the detail page for a video, JavaScript reads each dataset from Backblaze B2 and renders it into the page, allowing the user to easily navigate to any of the data items.

Searching the Index

When the user enters a query and hits the search button, the backend calls the Twelve Labs Search API, passing the query text, and requesting results for all four sources of information. We set group_by to video since we want to show the results by video, and set the confidence threshold to medium to improve the relevance of the results. From VideoSearchView in views.py:

results = TWELVE_LABS_CLIENT.search.query(
    TWELVE_LABS_INDEX_ID,
    query,
    ["visual", "conversation", "text_in_video", "logo"],
    group_by="video",
    threshold="medium"
)

By default, the query() call returns a page of 10 results in result.data, so we loop through the pages using next(result) to fetch pages of search results as necessary. Each individual search result includes start and end timecodes, confidence, and the type of match (visual, conversation, text, or logo).

In the web UI, the user can click through to the results for a given video, then click an individual search result to view the matching video clip.

Getting Started with Backblaze B2 and Twelve Labs

Backblaze B2 Cloud Storage is a great choice for storing video to index with Twelve Labs; free egress each month for up to three times the amount of data you’re storing means that you can submit your entire video library to the Twelve Labs platform without worrying about data transfer charges, and unlimited free egress to our CDN partners reduces the costs of distributing video content to end users.

Click here to create a Backblaze B2 account, if you don’t already have one. Your first 10GB of storage is free, no credit card required. If you’re an enterprise that wants to run a larger proof of concept, you can always reach out to our Sales Team. You don’t need to write any code to upload video files or create presigned URLs, and you can use the Backblaze web UI to upload files up to 500MB, or any of a wide variety of tools to upload files up to 10TB, including the AWS CLI, rclone and Cyberduck. Select S3 as the protocol to be able to create presigned URLs.

Similarly, click here to sign up for Twelve Labs’ Free plan. With it, you can index up to 600 minutes of video, again, no credit card required. Python and Node.js developers can use one of the Twelve Labs SDKs, while the Twelve Labs API documentation includes code examples for a wide range of other programming languages.

The post AI Video Understanding in Your Apps with Twelve Labs and Backblaze appeared first on Backblaze Blog | Cloud Storage & Cloud Backup
Backblaze Wins NAB Product of the Year

Post Syndicated from Jeremy Milk original https://backblaze.com/blog/backblaze-wins-nab-product-of-the-year/

A decorative image showing a film strip flowing into a cloud with the Backblaze and NAB Show logos displayed.

Last week the Backblaze team connected with the best and brightest of the media and entertainment industry at the National Association of Broadcasters (NAB) conference in Las Vegas. For those who missed out, here is a recap of last week events:

Event Notifications Launches at NAB 2024

Event Notifications gives you the freedom to build automated workflows across the different best-of-breed cloud platforms you use or want to use—saving time, money, and improving your end users’ experiences. After demoing this new service for folks working across media workflows at the NAB show and winning the NAB Product of the Year in the Cloud Computing and Storage category, the Event Notifications private preview list is filling up, but you can still join it today

A photograph of the 2024 Product of the Year trophy. Backblaze won this award for their new feature, Event Notifications.

Backblaze B2 Cloud Storage Event Notifications Wins NAB Best of Show Product of the Year

Join the Waitlist ➔ 

Backblaze Achieves TPN Blue Shield Status

More news for media and entertainment leaders: Backblaze joined the Trusted Partner Network (TPN), receiving Blue Shield status. TPN is the Motion Picture Association’s initiative aimed at advancing trust and security best practices across the media and entertainment industry. This important initiative provides greater transparency and confidence in the procurement process as you advance your workflow with new technology. 

Axle AI Cloud is Powered by Backblaze

A testament to the power of partnerships across the industry, Axel AI announced Axel AI Cloud Powered by Backblaze, a new, highly affordable, AI-powered media storage service that leverages Backblaze’s new Powered by Backblaze program for affordable, seamlessly integrated AI tagging, transcription, and search.

Experts on Stage

For the first time, Backblaze hosted a series of events together with Partners and customers, delivering actionable insights for folks on the show floor to improve their own media workflows. Our Backblaze Tech Talks featured Quantum, CuttingRoom, iconik, ELEMENTS, Axel AI, CloudSoda, Hedge, bunny.net, Suite Studios, and Qencode. Huge thanks to the presenters and everyone who came by.

See You at the Next One

Thank you to all of our customers, partners, and friends who helped make last week a hit. We are already looking forward to NAB–NY, IBC, NAB 2025—and, most of all, to moving the industry forward together. 

The post Backblaze Wins NAB Product of the Year appeared first on Backblaze Blog | Cloud Storage & Cloud Backup
Automate Your Data Workflows with Backblaze B2 Event Notifications

Post Syndicated from Bala Krishna Gangisetty original https://www.backblaze.com/blog/announcing-event-notifications/

A decorative image showing the Backblaze logo on a cloud with an alert notification.

Public Preview Update: July 31, 2024

Backblaze Event Notifications is now in public preview. If you’re interested in joining the waitlist, feel free to sign up here.

Backblaze believes companies should be able to store, use, and protect their data in whatever way is best for their business—and that doing so should be easy. That’s why we’re such fierce advocates for the open cloud and why today’s announcement is so exciting.

Event Notifications—available in public preview—gives businesses the freedom to build automated workloads across the different best-of-breed cloud platforms they use or want to use, saving time and money and improving end user experiences.

Here’s how: With Backblaze Event Notifications, any data changes within Backblaze B2 Cloud Storage—like uploads, updates, or deletions—can automatically trigger actions in a workflow, including transcoding video files, spooling up data analytics, delivering finished assets to end users, and many others. Importantly, unlike many other solutions currently available, Backblaze’s service doesn’t lock you into one platform or require you to use legacy tools from AWS.

So, to businesses that want to create an automated workflow that combines different compute, content delivery networks (CDN), data analytics, and whatever other cloud service: Now you can, with the bonus of cloud storage at a fifth of the rates of other solutions and free egress.

If you’re already a Backblaze customer, you can join the waiting list for the Event Notifications preview by signing up here. Once you’re admitted to the preview, the Event Notifications option will become visible in your Backblaze B2 account.

A screenshot of the where to find Event Notifications in your Backblaze account.

Not a Backblaze customer yet? Sign up for a free Backblaze B2 account and join the waitlist. Read on for more details on how Event Notifications can benefit you.

With Event Notifications, we can eliminate the final AWS component, Simple Queue Service (SQS), from our infrastructure. This completes our transition to a more streamlined and cost-effective tech stack. It’s not just about simplifying operations—it’s about achieving full independence from legacy systems and future-proofing our infrastructure.


— Oleh Aleynik, Senior Software Engineer and Co-Founder at CloudSpot.

A Deeper Dive on Backblaze’s Event Notifications Service

Event Notifications is a service designed to streamline and automate data workflows for Backblaze B2 customers. Whether it’s compressing objects, transcoding videos, or transforming data files, Event Notifications empowers you to orchestrate complex, multistep processes seamlessly.

The top line benefit of Event Notifications is its ability to trigger processing workflows automatically whenever data changes on Backblaze B2. This means that as soon as new data is uploaded, changed, or deleted, the relevant processing steps can be initiated without manual intervention. This automation not only saves time and resources, but it also ensures that workflows are consistently executed with precision, free from human errors.

What sets Event Notifications apart is its flexibility. Unlike some other solutions that are tied to specific target services, Event Notifications allows customers the freedom to choose the target services that best suit their needs. Whether it’s integrating with third-party applications, cloud services, or internal systems, Event Notifications seamlessly integrates into existing workflows, offering unparalleled versatility.

Finally, Event Notifications doesn’t only bring greater ease and efficiency to workflows, it is also designed for very easy enablement. Whether via browser UI or SDKs or APIs or CLI, it is incredibly simple to set up a notification rule and integrate it with your preferred target service. Simply choose your event type, set the criteria, and input your endpoint URL, and a new workflow can be configured in minutes.

Public Preview Update: July 31, 2024

Additional capabilities offered in the public preview include:

  • Retries: Event Notifications are automatically re-sent if the initial delivery attempt fails. This feature increases the reliability of Event Notifications by ensuring that temporary issues do not result in missed events, thus maintaining the integrity of your event-driven workflows.
  • Delivery: Event Notifications are designed for the at-least-once delivery guarantee to ensure Event Notifications are delivered reliably, even in the presence of network or system failures.

What Is Backblaze B2 Event Notifications Good For?

By leveraging Event Notifications, Backblaze B2 customers can simplify their data processing pipelines, reduce manual effort, and increase operational efficiency. With the ability to automate repetitive tasks and handle millions of objects per day, businesses can focus on extracting insights from their data rather than managing the logistics of data processing.

A diagram showing the steps of event notifications.

Automating tasks: Event Notifications allows users to trigger automated actions in response to changes in stored objects like upload, delete, and hide actions, streamlining complex data processing tasks.

Orchestrating workflows: Users can orchestrate multi-step workflows, such as compressing files, transcoding videos, or transforming data formats, based on specific object events.

Integrating with services: The feature offers flexible integration capabilities, enabling seamless interaction with various services and tools to enhance data processing and management.

Monitoring changes: Users can efficiently monitor and track changes to stored objects, ensuring timely responses to evolving data requirements and faster security response to safeguard critical assets.

What Are Some of the Key Capabilities of Backblaze B2 Event Notifications?

  • Flexible Implementation: Event Notifications are sent as HTTP POST requests to the desired service or endpoint within your infrastructure or any other cloud service. This flexibility ensures seamless integration with your existing workflows. For instance, your endpoint could be Fastly Compute, AWS Lambda, Azure Functions, or Google Cloud Functions, etc.
  • Event Categories: Specify the types of events you want to be notified about, such as when files are uploaded and deleted. This allows you to receive notifications tailored to your specific needs. For instance, you have the flexibility to specify different methods of object creation, such as copying, uploading, or multipart replication, to trigger event notifications. You can also manage Event Notification rules through UI or API.
  • Filter by Prefix: Define prefixes to filter events, enabling you to narrow down notifications to specific sets of objects or directories within your storage on Backblaze B2. For instance, if your bucket contains audio, video, and text files organized into separate prefixes, you can specify the prefix for audio files to receive event notifications exclusively for audio files.
  • Custom Headers: Include personalized HTTP headers in your event notifications to provide additional authentication or contextual information when communicating with your target endpoint. For example, you can use these headers to add necessary authentication tokens or API keys for your target endpoint, or include any extra metadata related to the payload to offer contextual information to your webhook endpoint, and more.
  • Signed Notification Messages: You can configure outgoing messages to be signed by the Event Notifications service, allowing you to validate signatures and verify that each message was generated by Backblaze B2 and not tampered with in transit.
  • Test Rule Functionality: Validate the functionality of your target endpoint by testing event notifications before deploying them into action. This allows you to ensure that your integration with your target endpoint is set up correctly and functioning as expected.

Want to Learn More About Event Notifications?

Event Notifications represents a significant advancement in data management and automation for Backblaze B2 users. By providing a flexible and powerful capability for orchestrating data processing workflows, Backblaze continues to empower businesses to unlock the full potential of their data with ease and efficiency.

Join the Waitlist ➔ 

The post Automate Your Data Workflows with Backblaze B2 Event Notifications appeared first on Backblaze Blog | Cloud Storage & Cloud Backup
Join Backblaze Tech Talks at NAB 24

Post Syndicated from James Flores original https://backblazeprod.wpenginepowered.com/blog/join-backblaze-tech-talks-at-nab-24/

A decorative image showing a film strip flowing into a cloud with the Backblaze and NAB Show logos displayed.

For those of you attending NAB 2024 (coming up in Las Vegas from April 14–17), we’re excited to invite you to our Backblaze Tech Talk series in booth SL7077. This series will deliver insights from expert guest speakers from a range of media workflow service providers in conversation with Backblaze solution engineers. Whether you’re an experienced workflow architect or new to the industry, anyone attending will leave with actionable insights to improve their own media workflows. 

All presentations are free, open to attendees, and will be held in the Backblaze booth (SL7077). Bonus: Get scanned while you’re there for exclusive Backblaze swag.

Sunday, April 14:

  • 3:00 p.m.: Leslie Hathaway, Sales Engineer and Brian Scheffler, Pre-Sales Sys. Engineer at Quantum discuss AI tools, CatDV Classic & .io utilizing Backblaze for primary storage.  

Monday, April 15:

  • 10:00 a.m.: Helge Høibraaten, Co-Founder of CuttingRoom presents “Cloud-Powered Remote Production: Collaborative Video Editing on the Back of Backblaze.”
  • 11:00 a.m.: Mattia Varriale, Sales Director EMEA at Backlight presents “Optimizing Media Workflow: Leveraging iconik and Backblaze for Cost-Effective, Searchable Storage.”
  • 1:00 p.m.: Danny Peters, VP of Business Development, Americas at ELEMENTS presents “Bridging On-Premises and Cloud Workflows: The ELEMENTS Media Ecosystem.”
  • 2:00 p.m.: Sam Bogoch, CEO at Axle AI with a new product announcement that is Powered by Backblaze.
  • 3:00 p.m.: Greg Hollick, Chief Product Officer and Co-Founder at CloudSoda presents “Effortless Integration: Automating Media Assets into Backblaze with CloudSoda.”

Tuesday, April 16:

  • 10:00 a.m.: Raul Vecchione, from Product Marketing at bunny.net presents “Edge Computing—Just Smarter.”
  • 11:00 a.m.: Paul Matthijs Lombert, CEO at Hedge presents “Every Cloud Workflow Starts at the (H)edge.”    
  • 1:00 p.m.: Craig Hering, Co-Founder & CEO of Suite Studios presents “Suite Studios and Backblaze Integration Providing Direct Access to Your Data for Real-Time Editing and Archive.”
  • 2:00 p.m.: Murad Mordukhay, CEO of Qencode presents “Building an Efficient Content Repository With Backblaze.”

Don’t miss out on these great tech talks. Elevate your expertise and connect with fellow media  industry leaders. We look forward to seeing you at NAB! And, if you’re ready to sit down and take a deep dive into your storage needs, book a meeting here.

The post Join Backblaze Tech Talks at NAB 24 appeared first on Backblaze Blog | Cloud Storage & Cloud Backup.

Managing the Media Tidal Wave: Backlight iconik’s 2024 Media Report

Post Syndicated from Jennifer Newman original https://backblazeprod.wpenginepowered.com/blog/managing-the-media-tidal-wave-backlight-iconiks-2024-media-report/

A decorative image showing several types of files falling into the a cloud with the Backblaze logo on it.

Everyone knows we’re living through an exceptional time when it comes to media production: Every day we experience a tidal wave of content—social video, virtual reality (VR) and augmented reality (AR) gaming, 10K sports footage, every streaming option imaginable—crashing down on us.

Two eye popping stats underscore that this perception is real: In December, Netflix shared that its users streamed close to 100 billion hours of content on its platform during the first half of 2023. At the beginning of 2024, YouTube revealed that its users watch one billion hours of video daily. 

It’s hard to make sense of that volume of content, it’s even harder to understand how it’s produced. Imagine the armies of people and types of programs required to capture, ingest, transcode, store, tag, edit, distribute, and archive all of it. Managing that content means touching every stage, start to finish, of the production process through the data lifecycle. 

A photo showing a woman surrounded by glistening raindrops, some of which transform into media icons.

To further complicate things, the modern production person’s workflow is nothing close to linear. They have to deal with:

  • A diversity of inputs: Content is pouring in from various sources. Keeping track of all this content, ensuring its quality, and organizing it effectively can feel like trying to catch a waterfall in a teacup. 
  • A variety of formats and file types: Each platform or device may require a different format or resolution, making it difficult to maintain consistency across the board and adding another layer of complexity.
  • Managing metadata, or indexing and tagging: With so much content flying around, ensuring that each file is properly tagged with relevant information is crucial for easy retrieval and management. However, manually inputting metadata for every piece of media can be time-consuming and prone to errors.
  • Remote and in-person collaboration: With team members spread across different locations, coordinating efforts and maintaining version control can be a headache.
  • Storage and scalability: As the volume of media grows, so does the need for storage space. Finding a solution that can accommodate this growth without breaking the bank can be tough.

While many companies are jumping in to provide tools to manage this tidal wave of content, one company, Backlight iconik, differentiates itself by providing industry-leading tools and offering public media reports on the state of media data today.

Backlight iconik’s 2024 Media Stats Report

Since 2018, iconik has provided a cloud-based media asset management (MAM) tool to help production professionals tame the insanity of modern content development. For the past four years, they’ve also provided an annual Media Stats report to help the industry understand the type of media being developed and distributed, as well as where and how it’s stored. (In 2022, Backlight, a global media technology, acquired iconik, hence the name change.) If you want the full story, please check out Backlight iconik’s 2024 Media Stats Report,

As cloud storage specialists here at Backblaze (and, lovers of stats ourselves), we would like to dig into their stats on storage and offer our own take here for you today.

2024 Media Storage Trend: The Content Tidal Wave Is Not a Mirage

According to Backlight iconik’s Media Stats Report, iconik’s data exploded to 152PB, shooting up by a whopping 57%—that’s 53PB more than in 2023. To put it in perspective, that’s roughly 6TB of fresh data pouring in every hour. This surge in data can be attributed to both new customers integrating their archives with iconik and existing customers ramping up their usage.

2024 Media Storage Trend: Audio on the Rise

An interesting find in their study was the difference between audio and video asset growth. Iconik is now managing 328 years of video (up 41% YoY) and 208 years of audio (up 50% YoY).

A decorative display of media stats from iconik's media report. The title reads Asset Duration. On the left, a blue circle displays the words 328 years of video, which represents 41% growth year on year. On the right, an orange circle contains the words 208 years of audio, which represents 50% growth year on year.
Note that “duration” in this context is measuring the total hours of runtime for each file. Source.

Over the last year, the growth of audio assets managed by Backlight iconik has surged, surpassing that of video, with a staggering 1,700 hours being added daily. They believe this surge is closely tied to the remarkable expansion of both the podcasting and audiobook markets in recent years. The global podcast market ballooned to $17.9 billion in 2023 and is forecasted to soar to $144 billion by 2032. Similarly, the audiobook market is projected to hit $35 billion by 2030, with expected revenue of $35.05 billion in the same year. While audio files are smaller than video files by far, it’s reasonable to anticipate a continued upward trajectory for audio assets across the media and entertainment landscape.

2024 Trend: The Shift to Cloud Storage for Cost-Effective Storage and Collaboration

According to Backlight iconik’s 2024 Media Stats Report, the trend toward cloud storage is definitely on the rise as the increased competition in the market and move away from hyperscalers drive more reasonable pricing. Companies are opting to transition to the cloud at their own speed, and hybrid cloud setups give them the freedom to shift assets as needed to improve things like performance, ease of access, security, and meeting regulatory requirements.

Get Ahead of the Wave: Pair iconik With Modern Cloud Storage Today

The reasons so many media professionals are moving to cloud are relatively simple: Cloud workflows enable enhanced collaboration and flexibility, greater cost predictability, and heightened security and management capabilities. And often, all of the above is possible at a lower total cost than legacy solutions.

Pairing Backlight iconik and Backblaze provides a simple solution for users to manage, collaborate, and store media projects easily. By integrating with iconik, Backblaze boosts workflow effectiveness, delivering a strong cloud-based MAM system that allows thorough management of Backblaze B2 Cloud Storage data right from a web browser.

Customer Story: How One Streaming Company Tackled Remote Content Workflows With Backblaze and Backlight iconik

When Goalcast, the empowering media company, decided to dive into making their own content, they realized their current setup just wasn’t cutting it. With their team spread out all over the place, they needed an easy way to get footage, access videos from anywhere, and keep a stash of finished files ready to jazz up for YouTube, Facebook, Instagram, Snapchat, TikTok, and the Goalcast OTT app. 

Goalcast combined LucidLink’s cloud-based workflows, iconik’s media asset manager and uploader features, and Backblaze B2 Cloud Storage. The integration between iconik, LucidLink, and Backblaze creates a slick media workflow. The content crew uploads raw footage straight into iconik, tossing in key details. Original files zip into Goalcast’s Backblaze B2 Bucket automatically, while edited versions are up for grabs via LucidLink. After the editing magic, final assets kick back into Backblaze B2.

The integration and partnership means endless possibilities for Goalcast. They’re saving around 150 hours a month in grunt work and stress. Now, they don’t have to fret about where footage hides or how to snag it—it’s all securely stored in Backblaze, ready for anyone on the team to grab, no matter where they’re working from.

You can get lost in the weeds of tech companies and storage solutions. It can hurt your brain. The sweet spot is these three—iconik, LucidLink, and Backblaze—and how they work together.

—Dan Schiffmacher, Production Operations Manager, Goalcast

2024 Media Mega Trend

Looking at Backlight iconik’s numbers and forecasts from a 25,000 foot vantage point makes one thing painfully clear: Effective media management and storage are going to be absolutely crucial for media teams to succeed in the future landscape of production. Dive deeper into how Backblaze and Backlight iconik can support you now and down the road, ensuring seamless media management, and affordable storage, that creates easy, stress-free expansion as your data continues to grow. 

Already have iconik and want to get started with Backblaze? Click here. 

The post Managing the Media Tidal Wave: Backlight iconik’s 2024 Media Report appeared first on Backblaze Blog | Cloud Storage & Cloud Backup.

A Disaster Recovery Game Plan for Media Teams

Post Syndicated from James Flores original https://www.backblaze.com/blog/a-disaster-recovery-game-plan-for-media-teams/

A decorative image showing icons representing file types surrounding a cloud. The background has sports imagery incorporated.

When it comes to content creation, every second you can spend honing your craft counts. Which means things like disaster recovery planning are often overlooked—they’re tasks that easily get bumped to the bottom of every to-do list. Yet, the consequences of data loss or downtime can be huge, affecting everything from marketing strategy to viewer engagement. 

For years, LTO tape has been a staple in disaster recovery (DR) plans for media teams that focus on everything from sports teams to broadcast news to TV and film production. Using an on-premises network attached storage (NAS) backed up to LTO tapes stored on-site, occasionally with a second copy off-site, is the de facto DR strategy for many. And while your off-site backup may be in a different physical location, more often than not, it’s the same city and still vulnerable to some of the same threats.  

As in all areas of business, the key to a successful DR plan is preparation. Having a solid DR plan in place can be the difference between bouncing back swiftly or facing downtime. Today, I’ll lay out some of the challenges media teams face with disaster recovery and share some of the most cost-effective and time-efficient solutions.

Disaster Recovery Challenges

Let’s dive into some potential issues media teams face when it comes to disaster recovery.

Insufficient Resources

It’s easy to deprioritize disaster recovery when you’re facing budgetary constraints. You’re often faced with a trade-off: protect your data assets or invest in creating more. You might have limited NAS or LTO capacity, so you’re constantly evaluating what is worthy of protecting. Beyond cost, you might also be facing space limitations where investing in more infrastructure means not just shouldering the price of new tapes or drives, but also building out space to house them.

Simplicity vs. Comprehensive Coverage: Keeping Up With Scale

We’ve all heard the saying “keep it simple, stupid.” But sometimes you sacrifice adequate coverage for the sake of simplicity. Maybe you established a disaster recovery plan early on, but haven’t revisited it as your team scaled. Broadcasting and media management can quickly become complex, involving multiple departments, facilities, and stakeholders. If you haven’t revisited your plan, you may have gaps in your readiness to respond to threats. 

As media teams grow and evolve, their disaster recovery needs may also change, meaning disaster recovery backups should be easy, automated, and geographically distanced. 

The LTO Fallacy

No matter how well documented your processes may be, it’s inevitable that any process that requires a physical component is subject to human error. And managing LTO tapes is nothing if not a physical process. You’re manually inserting LTO tapes into an LTO deck to perform a backup. You’re then physically placing that tape and its replicas in the correct location in your library. These processes have a considerable margin of error; any deviation from an established procedure compromises the recovery process.

Additionally, LTO components—the decks and the tapes themselves—age like any other piece of equipment. And ensuring that all appropriate staff members are adequately trained and aware of any nuances of the LTO system becomes crucial in understanding the recovery process. Achieving consistent training across all levels of the organization and maintaining hardware can be challenging, leading to gaps in preparedness.

Embracing Cloud Readiness

As a media team faced with the challenges outlined above, you need solutions. Enter cloud readiness. Cloud-based storage offers unparalleled scalability, flexibility, and reliability, making it ideal for safeguarding media for teams large and small. By leveraging the power of the cloud, media teams can ensure seamless access to vital information from any location, at any time. Whether it’s raw footage, game footage, or final assets, cloud storage enables rapid recovery and minimal disruption in the event of a disaster.

Cloud Storage Considerations for Media Teams

Migrating to a cloud-based disaster recovery model requires careful planning and consideration. Here are some key factors for sports teams to keep in mind:

  1. Data Security: Content security is becoming more and more of a top priority with many in the media space concerned about footage leakage and the growing monetization of archival content. Ensure your cloud provider employs robust security measures like encryption, and verify compliance with industry standards to maintain data privacy, especially if your media content involves sensitive or confidential information. 
  2. Cost Efficiency: Given the cost of NAS servers, LTO tapes, and external hard drives, scaling on-premises solutions indefinitely is not always the best solution. Extending your storage to the cloud makes scaling easy, but it’s not without its own set of considerations. Evaluate the cost structure of different cloud providers, considering factors like storage capacity, data transfer costs, and retention minimums.  
  3. Geospatial Redundancy: Driving LTO tapes to different locations or even shipping them to secure sites can become a logistical nightmare. When data is stored in the cloud, it not only can be accessed from anywhere but the replication of that data across geographic locations can be automated. Consider the geographical locations of the cloud servers to ensure optimal accessibility for your team, minimizing latency and providing a smooth user experience.
  4. Interoperability: With data securely stored in the cloud it becomes instantly accessible to not only users but across different systems, platforms, and applications. This facilitates interoperability with applications like cloud media asset managers (MAMs) or cloud editing solutions and even simplifies media distribution. When choosing a cloud provider, consider APIs and third-party integrations that might enhance the functionality of your media production environment. 
  5. Testing and Training: Testing and training are paramount in disaster recovery to ensure a swift and effective response when crises strike. Rigorous testing identifies vulnerabilities, fine-tunes procedures, and validates recovery strategies. Simulated scenarios enable teams to practice and refine their roles, enhancing coordination and readiness. Regular training instills confidence and competence, reducing downtime during actual disasters. By prioritizing testing and training, your media team can bolster resilience, safeguard critical data, and increase the likelihood of a seamless recovery in the face of unforeseen disasters.

Cloud Backup in Action
For Trailblazer Studios, a leading media production company, satisfying internal and external backup requirements led to a complex and costly manual system of LTO tape and spinning disk drive redundancies. They utilized Backblaze’s cloud storage to streamline their data recovery processes and enhance their overall workflow efficiency.

Backblaze is our off-site production backup. The hope is that we never need to use it, but it gives us peace of mind.

—Kevin Shattuck, Systems Administrator, Trailblazer Studios

The Road Ahead

As media continues to embrace digital transformation, the need for robust disaster recovery solutions has never been greater. By transitioning away from on-premises solutions like LTO tape and embracing cloud readiness, organizations can future-proof their operations and ensure uninterrupted production. And, while cloud readiness creates a more secure foundation for disaster recovery, having data in the cloud creates a pathway into the future teams can take advantage of a wave of cloud tools designed to foster productivity and efficiency. 

With the right strategy in place, media teams can turn potential disasters into mere setbacks, while taking advantage of their new cloud centric posterity maintaining their competitive edge. 

The post A Disaster Recovery Game Plan for Media Teams appeared first on Backblaze Blog | Cloud Storage & Cloud Backup.

How to Run AI/ML Workloads on CoreWeave + Backblaze

Post Syndicated from Pat Patterson original https://www.backblaze.com/blog/how-to-run-ai-ml-workloads-on-coreweave-backblaze/

A decorative image showing the Backblaze and CoreWeave logos superimposed on clouds.

Backblaze compute partner CoreWeave is a specialized GPU cloud provider designed to power use cases such as AI/ML, graphics, and rendering up to 35x faster and for 80% less than generalized public clouds. Brandon Jacobs, an infrastructure architect at CoreWeave, joined us earlier this year for Backblaze Tech Day ‘23. Brandon and I co-presented a session explaining both how to backup CoreWeave Cloud storage volumes to Backblaze B2 Cloud Storage and how to load a model from Backblaze B2 into the CoreWeave Cloud inference stack.

Since we recently published an article covering the backup process, in this blog post I’ll focus on loading a large language model (LLM) directly from Backblaze B2 into CoreWeave Cloud.

Below is the session recording from Tech Day; feel free to watch it instead of, or in addition to, reading this article.

More About CoreWeave

In the Tech Day session, Brandon covered the two sides of CoreWeave Cloud: 

  1. Model training and fine tuning. 
  2. The inference service. 

To maximize performance, CoreWeave provides a fully-managed Kubernetes environment running on bare metal, with no hypervisors between your containers and the hardware.

CoreWeave provides a range of storage options: storage volumes that can be directly mounted into Kubernetes pods as block storage or a shared file system, running on solid state drives (SSDs) or hard disk drives (HDDs), as well as their own native S3 compatible object storage. Knowing that, you’re probably wondering, “Why bother with Backblaze B2, when CoreWeave has their own object storage?”

The answer echoes the first few words of this blog post—CoreWeave’s object storage is a specialized implementation, co-located with their GPU compute infrastructure, with high-bandwidth networking and caching. Backblaze B2, in contrast, is general purpose cloud object storage, and includes features such as Object Lock and lifecycle rules, that are not as relevant to CoreWeave’s object storage. There is also a price differential. Currently, at $6/TB/month, Backblaze B2 is one-fifth of the cost of CoreWeave’s object storage.

So, as Brandon and I explained in the session, CoreWeave’s native storage is a great choice for both the training and inference use cases, where you need the fastest possible access to data, while Backblaze B2 shines as longer term storage for training, model, and inference data as well as the destination for data output from the inference process. In addition, since Backblaze and CoreWeave are bandwidth partners, you can transfer data between our two clouds with no egress fees, freeing you from unpredictable data transfer costs.

Loading an LLM From Backblaze B2

To demonstrate how to load an archived model from Backblaze B2, I used CoreWeave’s GPT-2 sample. GPT-2 is an earlier version of the GPT-3.5 and GPT-4 LLMs used in ChatGPT. As such, it’s an accessible way to get started with LLMs, but, as you’ll see, it certainly doesn’t pass the Turing test!

This sample comprises two applications: a transformer and a predictor. The transformer implements a REST API, handling incoming prompt requests from client apps, encoding each prompt into a tensor, which the transformer passes to the predictor. The predictor applies the GPT-2 model to the input tensor, returning an output tensor to the transformer for decoding into text that is returned to the client app. The two applications have different hardware requirements—the predictor needs a GPU, while the transformer is satisfied with just a CPU, so they are configured as separate Kubernetes pods, and can be scaled up and down independently.

Since the GPT-2 sample includes instructions for loading data from Amazon S3, and Backblaze B2 features an S3 compatible API, it was a snap to modify the sample to load data from a Backblaze B2 Bucket. In fact, there was just a single line to change, in the s3-secret.yaml configuration file. The file is only 10 lines long, so here it is in its entirety:

apiVersion: v1
kind: Secret
metadata:
  name: s3-secret
  annotations:
     serving.kubeflow.org/s3-endpoint: s3.us-west-004.backblazeb2.com
type: Opaque
data:
  AWS_ACCESS_KEY_ID: <my-backblaze-b2-application-key-id>
  AWS_SECRET_ACCESS_KEY: <my-backblaze-b2-application-key>

As you can see, all I had to do was set the serving.kubeflow.org/s3-endpoint metadata annotation to my Backblaze B2 Bucket’s endpoint and paste in an application key and its ID.

While that was the only Backblaze B2-specific edit, I did have to configure the bucket and path where my model was stored. Here’s an excerpt from gpt-s3-inferenceservice.yaml, which configures the inference service itself:

apiVersion: serving.kubeflow.org/v1alpha2
kind: InferenceService
metadata:
  name: gpt-s3
  annotations:
    # Target concurrency of 4 active requests to each container
    autoscaling.knative.dev/target: "4"
    serving.kubeflow.org/gke-accelerator: Tesla_V100
spec:
  default:
    predictor:
      minReplicas: 0 # Allow scale to zero
      maxReplicas: 2 
      serviceAccountName: s3-sa # The B2 credentials are retrieved from the service account
      tensorflow:
        # B2 bucket and path where the model is stored
        storageUri: s3://<my-bucket>/model-storage/124M/
        runtimeVersion: "1.14.0-gpu"
        ...

Aside from storageUri configuration, you can see how the predictor application’s pod is configured to scale from between zero and two instances (“replicas” in Kubernetes terminology). The remainder of the file contains the transformer pod configuration, allowing it to scale from zero to a single instance.

Running an LLM on CoreWeave Cloud

Spinning up the inference service involved a kubectl apply command for each configuration file and a short wait for the CoreWeave GPU cloud to bring up the compute and networking infrastructure. Once the predictor and transformer services were ready, I used curl to submit my first prompt to the transformer endpoint:

% curl -d '{"instances": ["That was easy"]}' http://gpt-s3-transformer-default.tenant-dead0a.knative.chi.coreweave.com/v1/models/gpt-s3:predict
{"predictions": ["That was easy for some people, it's just impossible for me,\" Davis said. \"I'm still trying to" ]}

In the video, I repeated the exercise, feeding GPT-2’s response back into it as a prompt a few times to generate a few paragraphs of text. Here’s what it came up with:

“That was easy: If I had a friend who could take care of my dad for the rest of his life, I would’ve known. If I had a friend who could take care of my kid. He would’ve been better for him than if I had to rely on him for everything.

The problem is, no one is perfect. There are always more people to be around than we think. No one cares what anyone in those parts of Britain believes,

The other problem is that every decision the people we’re trying to help aren’t really theirs. If you have to choose what to do”

If you’ve used ChatGPT, you’ll recognize how far LLMs have come since GPT-2’s release in 2019!

Run Your Own Large Language Model

While CoreWeave’s GPT-2 sample is an excellent introduction to the world of LLMs, it’s a bit limited. If you’re looking to get deeper into generative AI, another sample, Fine-tune Large Language Models with CoreWeave Cloud, shows how to fine-tune a model from the more recent EleutherAI Pythia suite.

Since CoreWeave is a specialized GPU cloud designed to deliver best-in-class performance up to 35x faster and 80% less expensive than generalized public clouds, it’s a great choice for workloads such as AI, ML, rendering, and more, and, as you’ve seen in this blog post, easy to integrate with Backblaze B2 Cloud Storage, with no data transfer costs. For more information, contact the CoreWeave team.

The post How to Run AI/ML Workloads on CoreWeave + Backblaze appeared first on Backblaze Blog | Cloud Storage & Cloud Backup.

Free Your Premiere Pro Workflows With Backblaze Cloud Storage

Post Syndicated from James Flores original https://www.backblaze.com/blog/free-your-premiere-pro-workflows-with-backblaze-cloud-storage/

A decorative image showing a mockup of Premiere Pro's user interface and the Backblaze storage cloud.

Projects and technologies come and go, and with each new tool comes new workflow changes. But changing the way you move media around can be tough. Maybe you’ve always done things a certain way, and using a new tool feels like too much of a learning curve especially when you’re pressed for time. But the way you’ve always done things isn’t always the best, easiest, or fastest way. Sometimes you need to change the status quo to level up your media operations. 

As a freelance editor, I worked on a recent project that presented some challenges that demanded new approaches to media storage challenges you might also be facing. I solved them with the cloud—but not an all-in-one cloud. My solution was a mix of cloud tools, including Adobe Premiere Pro, which gives me customization and flexibility—the best of all worlds in media workflows

Right Opportunity at the Right Time

Last year I had the opportunity to serve as a digital imaging technician (DIT) on the set of an indie film titled “Vengeance” produced by Falcon Pictures. The role of a DIT can vary. In many instances you’re simply a data wrangler making backups of the data being shot. In others, you work in the color space of the project creating color corrected dailies on set. For “Vengeance”, I was mostly data wrangling. 

“Vengeance” was an 11-day shoot in the mountains of Northern California near Bass Lake. While the rest of the crew spent their days hiking around with equipment, I was stationed back at home base with my DIT cart. With a lot of free time, I found myself logging data as it came in. Logging clip names soon turned into organizing bins and prepping the project for editing. And, while I was not the editor on the project, I was happy to help edit while I was on set. 

The Challenge

A few months after my work as DIT ended, it became clear that “Vengeance” needed a boost in post-production. The editing was a bit stuck—they had no assistant editor to complete logging and to sound sync all the footage. So, I was asked to help out. The only problem: I needed to be able to share my work with another editor who lived 45 miles away.

A screenshot of an indie film, Vengeance, being edited in Adobe Premiere Pro.
Editing “Vengeance” in Adobe Premiere Pro.

Evaluating the World of Workflows and Cloud Tools

So we began to evaluate a few different solutions. It was clear that Adobe Premiere Pro would be used, but data storage was still a big question. We debated a few methods for sharing media:

  1. The traditional route: Sharing a studio. With the other editor 45 miles away, commuting and scheduling time with each other was going to be cumbersome. 
  2. Email: We could email project files back and forth as we worked, but how would we keep track of versioning? Project bloat was a big concern. 
  3. Sharing a shuttle drive. Or what I’m calling “Sneakernet 2.0.” This is a popular method, but far from efficient. 
  4. Google Drive or Dropbox: Another popular option, but also one that comes with costs and service limitations like rate limiting. 

None of these options were great, so we went back to the drawing board. 

The Solution: A Hybrid Workflow Designed for Our Needs

To come to a final decision for this workflow, we made a list of our needs: 

  • The ability to share a Premiere Pro project file for updates. 
  • The ability to share media for the project. 
  • No exchanging external hard drives. 
  • No driving (a car).  
  • Changes need to be real time.

Based on those needs, here’s where we landed.

Sharing Project Files

Adobe recently released a new update to its Team Projects features within Premiere Pro. Team Projects allows you to host a Premiere Pro project in the Adobe cloud and share it with other Adobe Creative Cloud users. This gave us the flexibility to share a single project and share updates in real time. This means no emailing of project files, versioning issues, or bloated files. That left the issues of the media. How do we share media? 

Sharing Media Files

You may think that it would be obvious to share files in the Adobe Creative Cloud where you get 100GB free. And while 100GB may be enough storage for .psd and .ai files, 100GB is nothing for video, especially when we are talking about RED (.r3d) files which start off as approximately 4GB chunks and can quickly add up to terabytes of footage. 

So we put everything in a Backblaze B2 Bucket. All the .r3d source files went directly from my Synology network attached storage (NAS) into a Backblaze B2 Bucket using the Synology Cloud Sync tool. In addition to the source files, I used Adobe Media Encoder to generate proxy files of all the .r3d files. This folder of proxy files also synced with Backblaze automatically. 

Making Changes in Real Time

What was great about this solution is that all of the uploading is done automatically via a seamless Backblaze + Synology integration, and the Premiere Pro Team Project had a slew of publish functions perfect for real-time updates. And because the project files and proxies are stored in the cloud, I could get to them from several computers. I spent time at my desktop PC logging and syncing footage, but was also able to move to my couch and do the same from my MacBook Pro. I never had to move hard drives around, copy projects files, or worry about version control.

The other editor was able to connect to my Backblaze B2 Bucket using Cyberduck, a cloud storage browser for Mac. Using Cyberduck, he was able to pull down all the proxy files I created and share any files that he created. So, we were synced for the entire duration of the project. 

Once the technology was configured, I was able to finish logging for “Vengeance”, sync all the sound, build out stringouts and assemblies, and even a rough cut of every scene for the entire movie, giving the post-production process the boost it needed.

A diagram showing how editors use Backblaze B2 Cloud Storage with Adobe Premiere Pro.

The Power of Centralized Storage for Media Workflows

Technology is constantly evolving, and, in most circumstances, technology makes how we work a lot easier. For years filmmakers have worked on projects by physically moving our source material, whether it was on film reels, tapes, or hard drives. The cloud changed all that

The key to getting “Vengeance” through post-production was our centralized approach to file management. Files existed in Backblaze already, we simply brought Premiere Pro to the data rather than moving the huge amount of files to Premiere Pro via the Creative Cloud. 

The mix of technologies lets us create a customized flow that works for us. Creative Cloud had the benefit of providing a project sharing mechanism, and Backblaze provided a method of sharing media (Synology and Cyberduck) regardless of the tooling each editor had. 

Once we hit picture lock, the centralized files will serve as a distribution point for VFX, color, and sound, making turnover a breeze. It can even be used as a distribution hub—check out how American Public Television uses Backblaze to distribute their finished assets. 

Centralizing in the cloud not only made it easy for me to work from home, it allowed us to collaborate on a project with ease eliminating the overhead of driving, shuttle drive delivery (Sneakernet 2.0), and version control. The best part? A workflow like this is affordable for any size production and can be set up in minutes. 

Have you recently moved to a cloud workflow? Let us know what you’re using and how it went in the comments. 

The post Free Your Premiere Pro Workflows With Backblaze Cloud Storage appeared first on Backblaze Blog | Cloud Storage & Cloud Backup.