Защо е малко вероятно в България да спечели демократичен президент

Post Syndicated from Светла Енчева original https://www.toest.bg/zashto-e-malko-veroyatno-v-bulgaria-da-specheli-demokratichen-prezident/

Защо е малко вероятно в България да спечели демократичен президент

През есента на 2026 г. в България предстоят избори за президент. Засега никоя политическа сила не е посочила своя кандидат за държавен глава, нито има ясна визия какви да са основните послания в кампанията. Не се знаят и конфигурациите, които биха застанали зад един или друг претендент. При толкова много неизвестни нека поне опитаме

да скицираме електоралния пейзаж.

Претендентите за поста може да се разделят с оглед на електоралната си база в три основни групи – две големи и една по-малка.

В първата са потенциалните евроскептични и повече или по-малко проруски кандидати. Там напливът е най-голям – „Възраждане“, „Величие“, БСП, ИТН, МЕЧ и всевъзможни „патриоти“. И най-важното – евентуален кандидат, ползващ се с подкрепата на настоящия президент, който е политикът с най-висок рейтинг в България.

Във втората ще е фаворитът на ГЕРБ/Пеевски. Това може да е лично Бойко Борисов или някой друг. В тази група не се очаква конкуренция, поне на видимо равнище. Идеологическият ѝ облик е аморфен – и Борисов, и Пеевски го играят в зависимост от конкретната ситуация и евроатлантици, и евроскептици, и почитатели на „силната ръка“. 

В третата група са идентифициращите се като демократични и проевропейски партии – „Продължаваме промяната“ и „Демократична България“ (коалицията между ДСБ и „Да, България“). До април 2024 г. и Зелено движение беше част от ДБ, но днес то по-скоро се държи като активистка група. Не участва в последните парламентарни избори и няма яснота ще вземе ли някакво отношение към президентските.

От мравешки и от птичи поглед

В редиците на ПП–ДБ и техните симпатизанти основната интрига е дали партиите ще се обединят около общ кандидат-президент, или различията и амбициите им ще надделеят.

Следващият по важност въпрос е какъв да бъде евентуалният консенсусен кандидат. „Нужно е лице, което вдъхва надежда, интегрира отвъд партийното ядро, комуникира ясно европейската посока и не се страхува да назове опонентите си“, казва Емилия Милчева.

Способността на кандидата да се хареса отвъд партийните ядра е особено важна, защото понастоящем ПП–ДБ могат да разчитат на подкрепата на има-няма 15% от гласоподавателите. Макар идеята за предварителни избори да звучи демократично, по всяка вероятност в тях биха се включили само твърдите електорати на партиите от коалицията. И няма гаранция, че спечелилият ще може да привлече широка периферия избиратели.

Ала докато в редиците на крехката коалиция ври и кипи, как изглежда ситуацията в сравнителен европейски план?

През 2025 г. се проведоха президентски избори в Румъния и Полша. И в двете страни кандидатите, стигнали до втория тур, бяха демократичен, който е и кмет на столицата, и евроскептичен/проруски.

В Румъния спечели демократичният кандидат. Това обаче стана от втория път – в края на 2024 г. резултатите от първия вот за президент, спечелен от евроскептичен кандидат, бяха отменени заради разузнавателни данни за намеса на Русия в изборния процес. В Полша спечели, макар и с малко, проруският кандидат.

И в Румъния, и в Полша, за разлика от България, има силни продемократични и проевропейски обществени настроения, довели до масови протести. В Румъния целта на протестите беше запазването на геополитическата ориентация на страната. В Полша имаше масово недоволство срещу консервативни реформи по времето на управлението на предишния премиер Ярослав Качински, като например забраната на абортите.

В България масови протести в името на демократични ценности на практика няма.

Демонстрациите против премахването на светския характер на българското образование например събраха няколко хиляди души – немалко, но далеч от масово. Недоволството срещу забраната на т.нар. ЛГБТ пропаганда в училище беше още по-бутиково, а насилието над жени мобилизира обществената енергия най-вече при конкретни случаи и бързо отшумява.

Борбата против корупцията и за правосъдна реформа не е непременно свързана с демократичните ценности. Тя може да се води и в името на установяване на управление на „силнатя ръка“, която „да сложи всичко в ред“. Друг въпрос е, че и антикорупцията вече не катализира особена обществена енергия.

Що се отнася до службите,

българското разузнаване предприе мерки срещу руското влияние в страната през 2022 г., когато на власт беше правителството в оставка на Румен Петков. И преди, и след това от ДАНС не изглежда да правят нещо. Въпреки

При такива служби кой би разследвал евентуална намеса на руското разузнаване в български избори?

Как се разширява периферия?

За да има шанс евентуален демократичен кандидат да спечели президентските избори, е необходима не само подходяща личност, която да увлича хората. Трябва да съществува и важна кауза, която да насочва обществената енергия в определена посока.

Междукоалиционните дрязги дали кандидатът да е по-десен, или по-либерален, дали да е утвърден политик, или надпартийно лице и т.н., изпускат от поглед голямата картина. А тя е, че който и да е кандидатът, той (или тя, макар да е малко вероятно родните демократи да рискуват да предложат жена) трудно ще намери какво да каже или да направи, така че да привлече избиратели, надхвърлящи електоралното ядро на ПП–ДБ в пъти.

Евроскептичните гласоподаватели трудно могат да бъдат привлечени с лозунги против корупцията след т.нар. сглобка – правителството на Николай Денков с участието на ГЕРБ. И с натрапената подкрепа на Делян Пеевски, който използва ПП–ДБ, за да „изсветли“ имиджа си.

Приказките за борба с корупцията и за правосъдна реформа

не могат да трогнат и електората на ГЕРБ и ДПС, както и голяма част от хората, които не гласуват, защото не виждат смисъл.

Представете си ресторантьорка от малък български град. Тя знае, че за да върви бизнесът ѝ без проблеми, трябва да е в добри отношения с кмета и с местните мутри, да им дава каквото и колкото поискат, и да гласува за когото ѝ кажат. През целия ѝ живот тя и всички около нея живеят по този начин. За нея говоренето за корупция и правосъдие е празни приказки.

А сега си представете международен шофьор на камион. Официално той получава минимална работна заплата, но понеже работодателите му пестят от осигуровки, под масата взема няколко хиляди лева на месец. Човекът се оставя да го експлоатират и се притеснява, че ако бизнесът на превозвачите се изсветли, самият той ще обеднее. И не гласува, защото смята, че държавата не го защитава по никакъв начин.

С какви послания евентуалният кандидат на ПП–ДБ би могъл да привлече поне няколкостотин хиляди избиратели като посочените в примерите?

Посланията

Логично е един демократичен и проевропейски претендент за държавен глава да отправя демократични и проевропейски послания. Проблемът е, че българските демократични и проевропейски партии почти не отправят такива.

И тук дори не става дума за теми като човешки права, от които в България комай всички политически сили бягат като дявол от тамян. А за елементарни неща – например, че демокрацията е за предпочитане пред диктатурата. Или че България по конституция е светска държава. Или защо е важно да има неправителствени организации и изобщо гражданско общество.

Впрочем сещате ли се за българска политическа позиция през последните години, в която да се казва какви точно са европейските ценности?

Когато демократичните и проевропейските партии не отправят демократични и проевропейски послания, дневният ред се задава от популистите. Затова демокрацията се асоциира с правото всякакви въпроси да могат да се решават на референдум, НПО-тата се заклеймяват като „соросоиди“, неодобрението за въвеждането на еврото е толкова високо, европейските ценности се възприемат като „еврогейски“ и т.н.

И ако демократичният и проевропейски кандидат-президент тепърва започне да отправя демократични и проевропейски послания, едва ли ще има много хора, които ще искат да ги чуят.

Затова най-реалистичната стратегия е да се разчита на прагматизма.

Тоест да не се говори за принципи и ценности, а за ползи и рискове – какво рискуваме, ако завием към Русия, и какво печелим, ако сме интегрирани в ЕС.

Хубаво, но на това поле вероятно ще се състезават също ГЕРБ/ДПС. И ще се хвалят, че благодарение на тях България е запазила проевропейския си курс и е приела еврото. Което е фактологически вярно.

В такъв случай стратегията на евентуалния демократичен кандидат би могла да е да ги разобличава, показвайки тяхната неавтентичност. Например да припомня, че енергийната зависимост на България от Русия беше практически бетонирана по време на правителствата на Борисов и че това се промени чак когато започна войната на Русия срещу Украйна. Че Борисов подари на Путин кученце. Че ГЕРБ не е направила нищо за ограничаването на руското влияние в България.

Може и да се припомня, че на председателя на ГЕРБ най-близки на сърцето са му евроскептици като Виктор Орбан и че самият той нерядко се държи като евроскептик. Както и че Пеевски мени геополитическите си позиции според ситуацията – в един момент той може да си припише заслуги пред Украйна, в следващия – да се обяви срещу изпращането на военна помощ там.

Но печеливша стратегия ли е това?

Дали на критична част от българските гласоподаватели изобщо ѝ пука кой е по-автентичен демократ и кой по-малко?

Големият проблем не е дали ПП–ДБ ще предложат общ кандидат, а как такъв кандидат би могъл да спечели изборите. След като с отказа си да отстояват демокрацията партиите, идентифициращи се като демократични, са допринесли самата демокрация вече да няма особено значение в България. А принадлежността към европейското семейство е изпразнена от ценностно съдържание.

Накрая на немногото демократични и проевропейски избиратели най-вероятно ще им остане да се надяват президентските избори да спечелят ГЕРБ/ДПС. Защото познатото корупционно и клонящо към авторитаризъм блато е за предпочитане пред резкия геополитически завой към Русия. Пък и блатото си го познаваме. Досега парламентът и редовните правителства успяваха в някаква степен да противодействат на пропутинската ориентация на Румен Радев. Но ако и новият президент е проруски настроен, това ще даде тласък на следващи парламентарни избори, на които е доста вероятно евроскептиците да постигнат мнозинство.

Такива са перспективите, освен ако не се случи някое събитие с огромна важност, което рязко да събуди демократичните инстинкти на населението. Поне засега такова не се очертава.
Podman Container Monitoring with Prometheus Exporter, part 2

Post Syndicated from Janis Eidaks original https://blog.zabbix.com/podman-container-monitoring-with-prometheus-exporter-part-2/30538/

In the first part of this post, we explored how to get data with HTTP agent from the Prometheus Podman exporter and use the same item data for the Podman pods Discovery rule as well as item and trigger prototypes. In part 2 of the same series, we’ll learn how to discover and monitor Podman containers.

Creating a template discovery rule

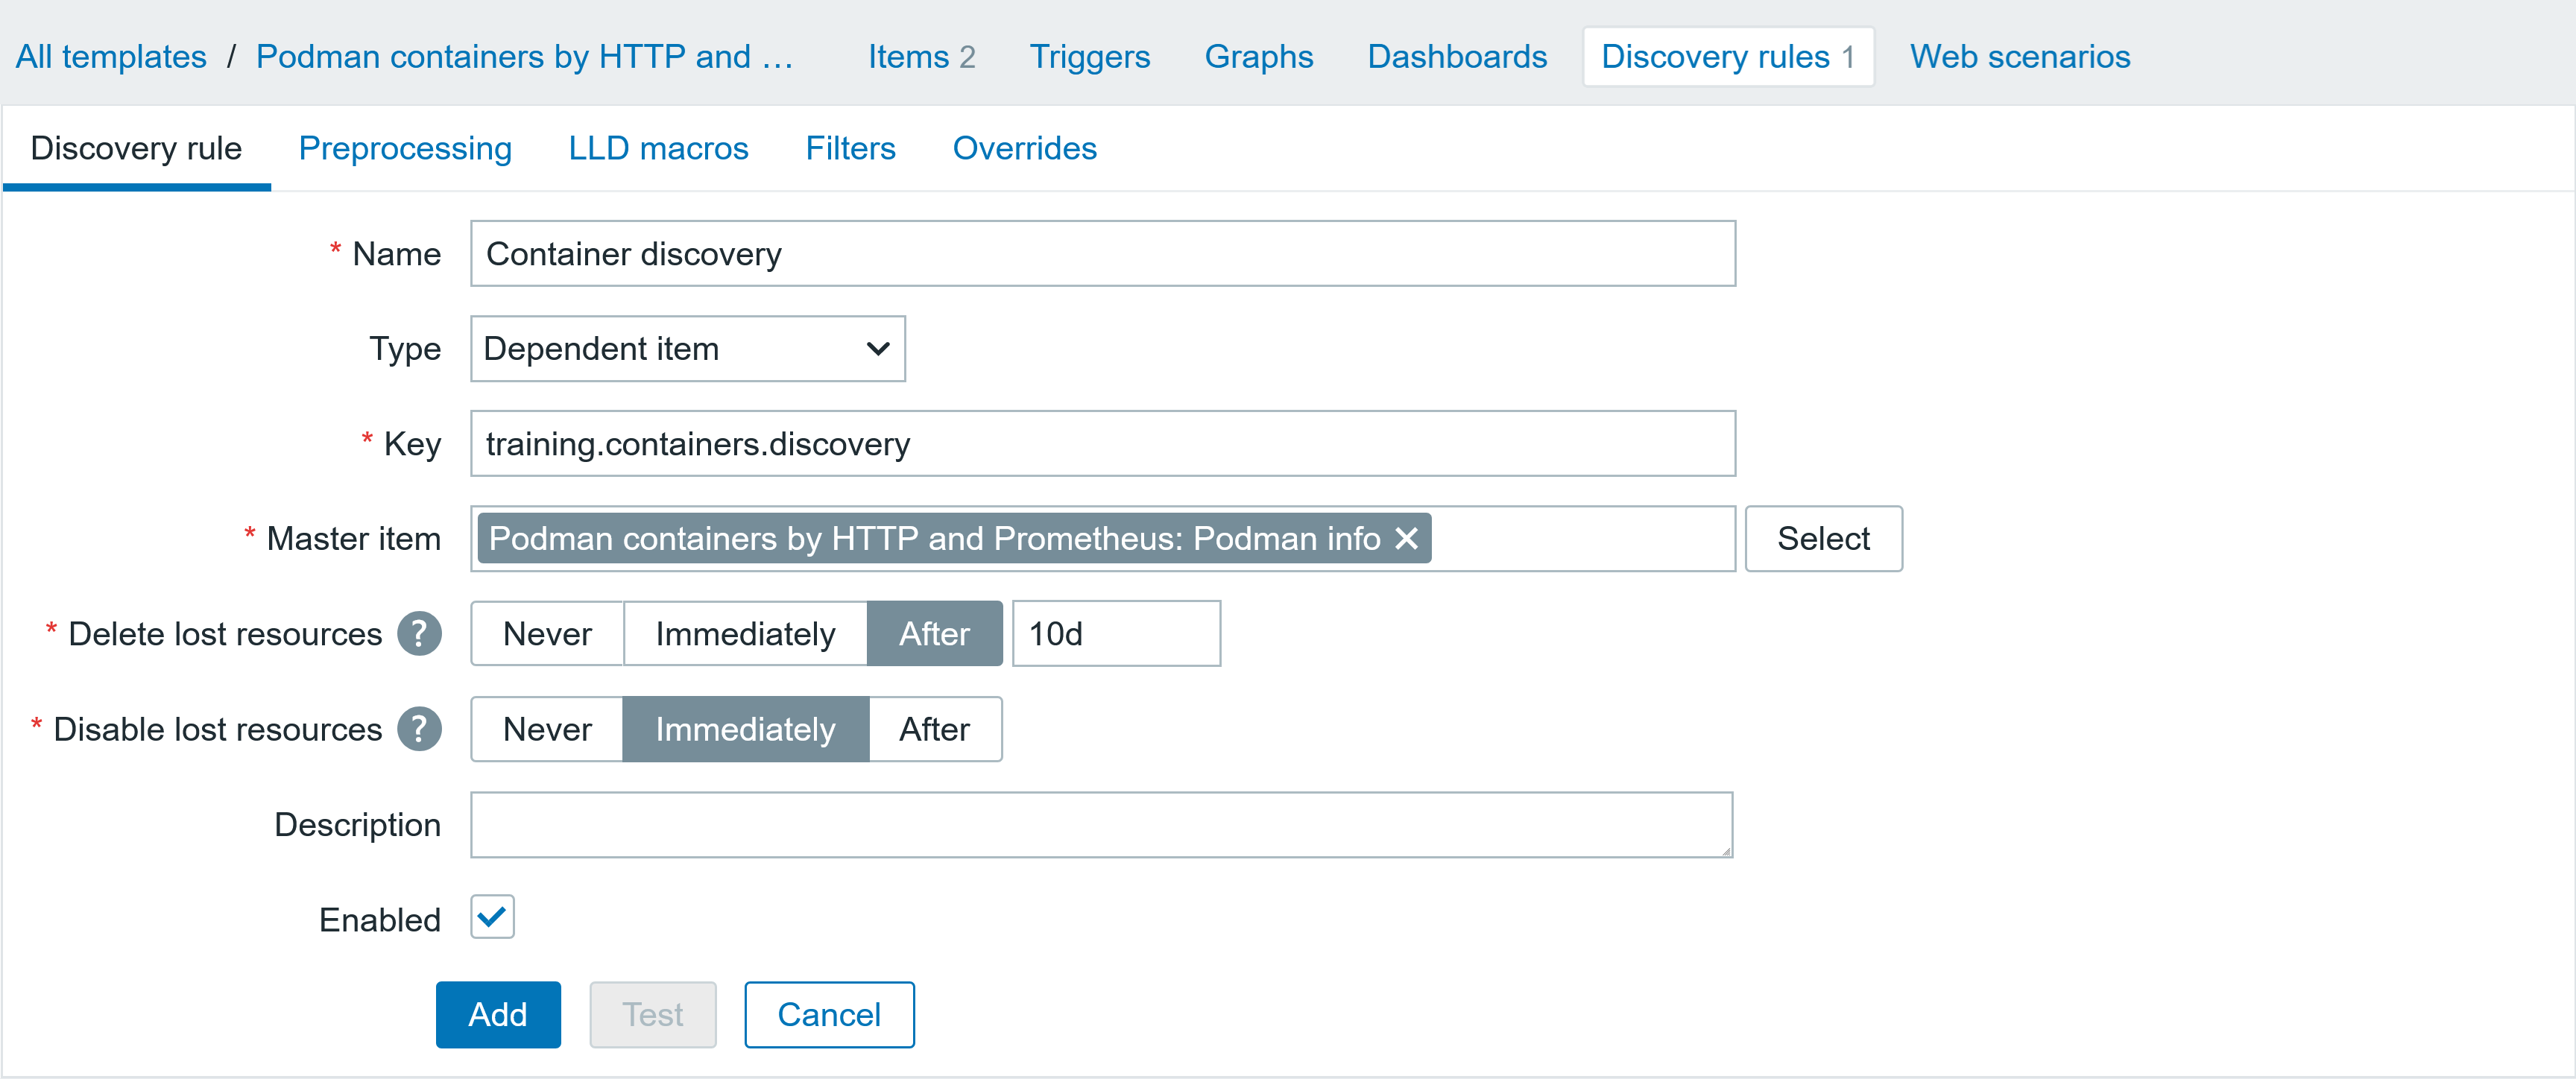
I will create another discovery rule for container discovery. This discovery rule is also based on the same item [Podman info] in the template – Podman containers by HTTP and Prometheus (you can check part one of this series to find out how to configure it). The parameters of the discovery rule are shown below. This discovery rule will allow us to discover the pod name and ID.

Template: Podman containers by HTTP and Prometheus

▲ Discovery rule
  ▪ Name:                   Container discovery
  ▪ Type                    Dependent item
  ▪ Key:                    training.containers.discovery
  ▪ Master item             Podman containers by HTTP and Prometheus: Podman info
  ▪ Delete lost resources  After 10d
  ▪ Disable lost resources Immediately
♯ Preprocessing
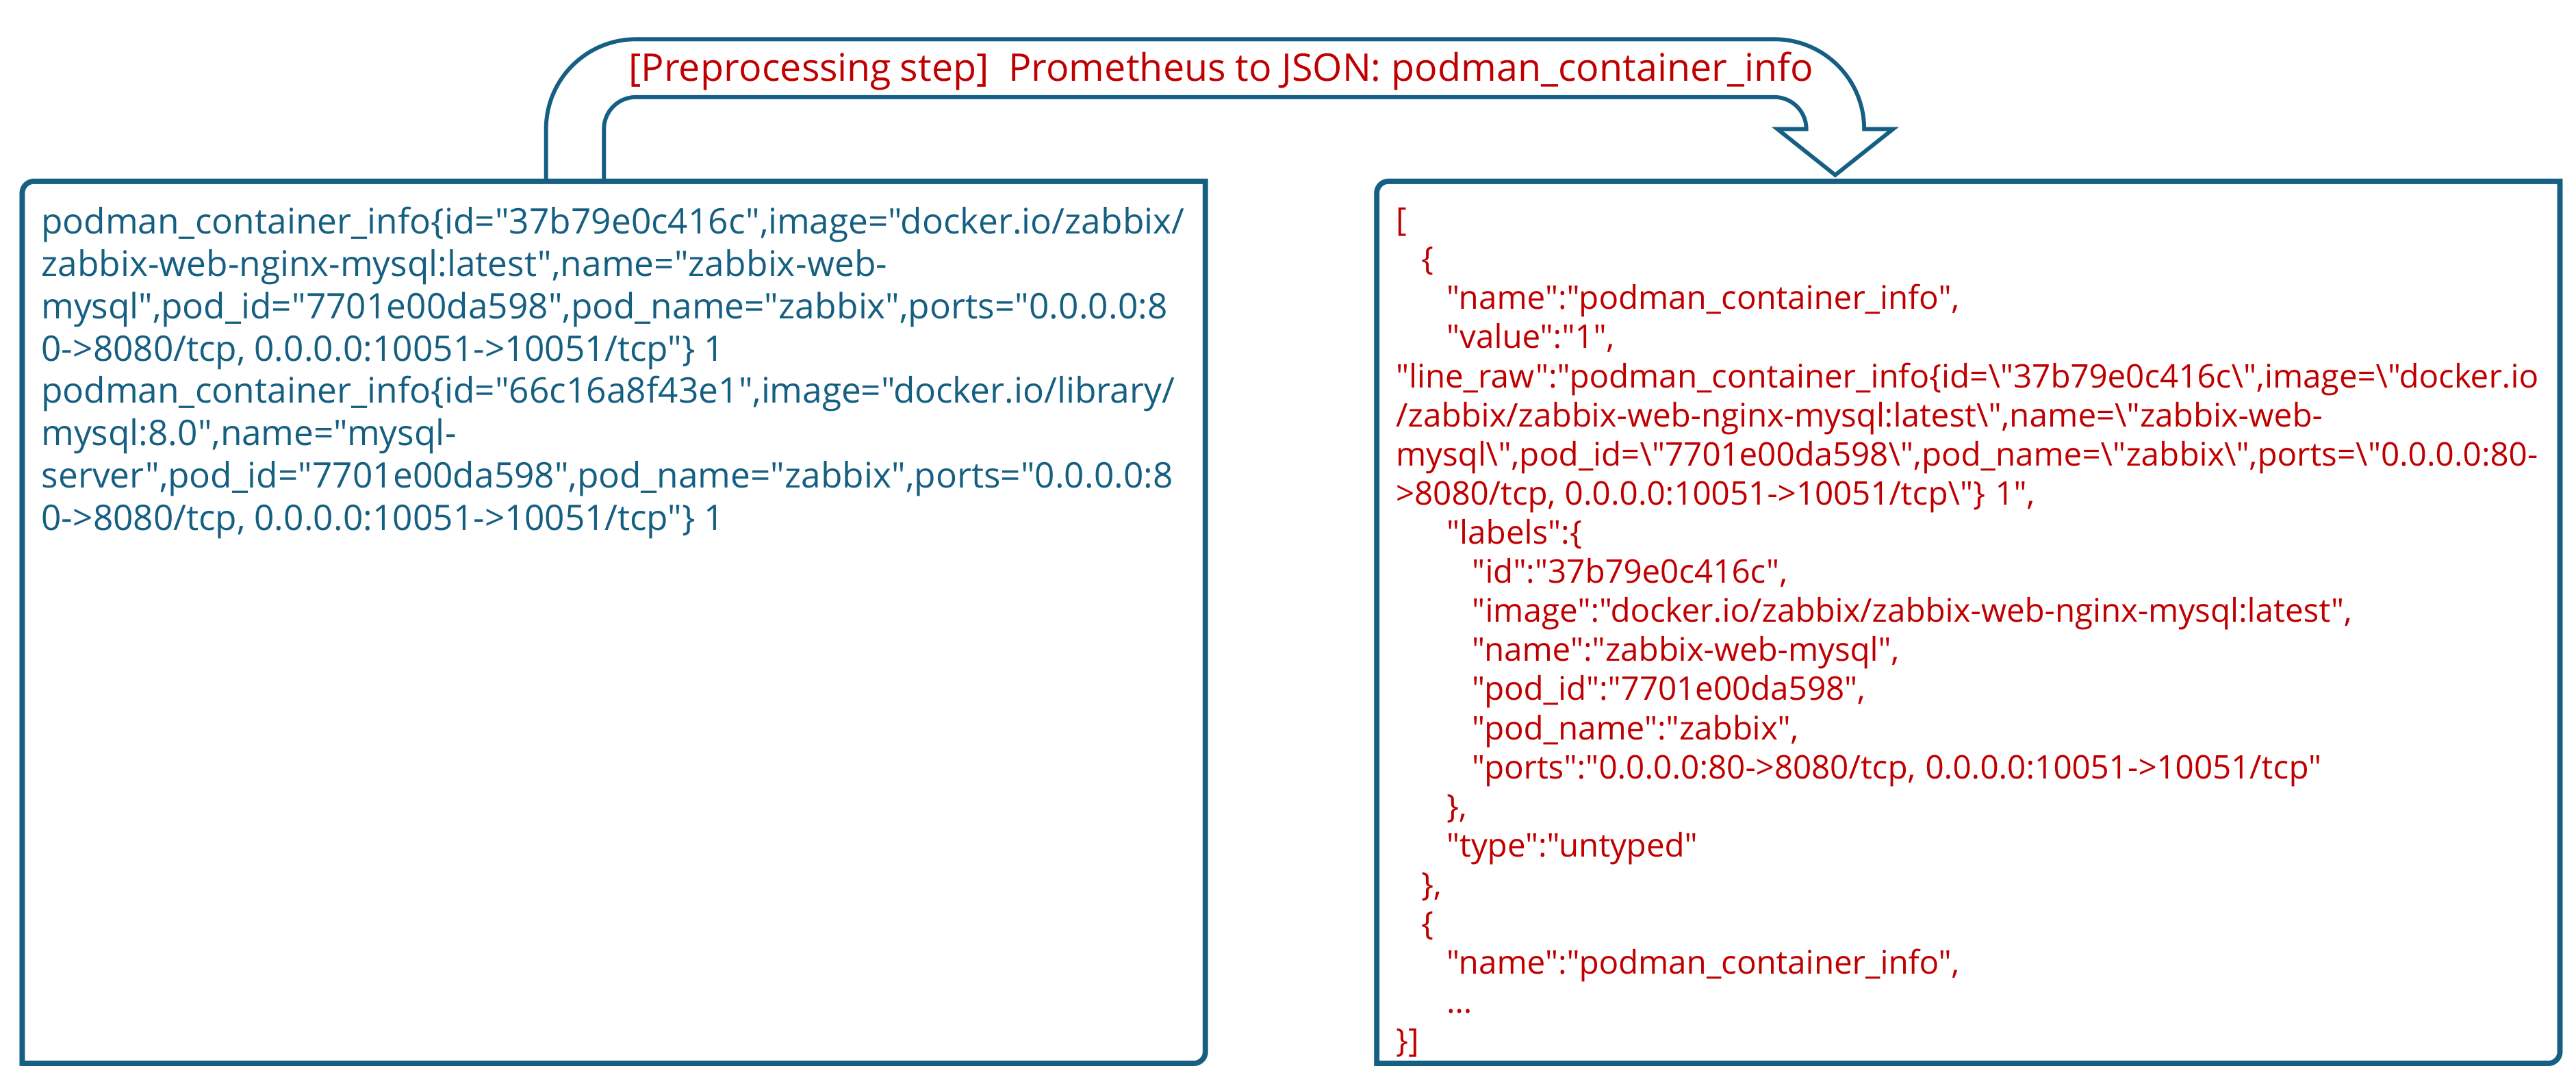
  ▪ Prometheus to JSON     podman_container_info
♦ LLD Macros
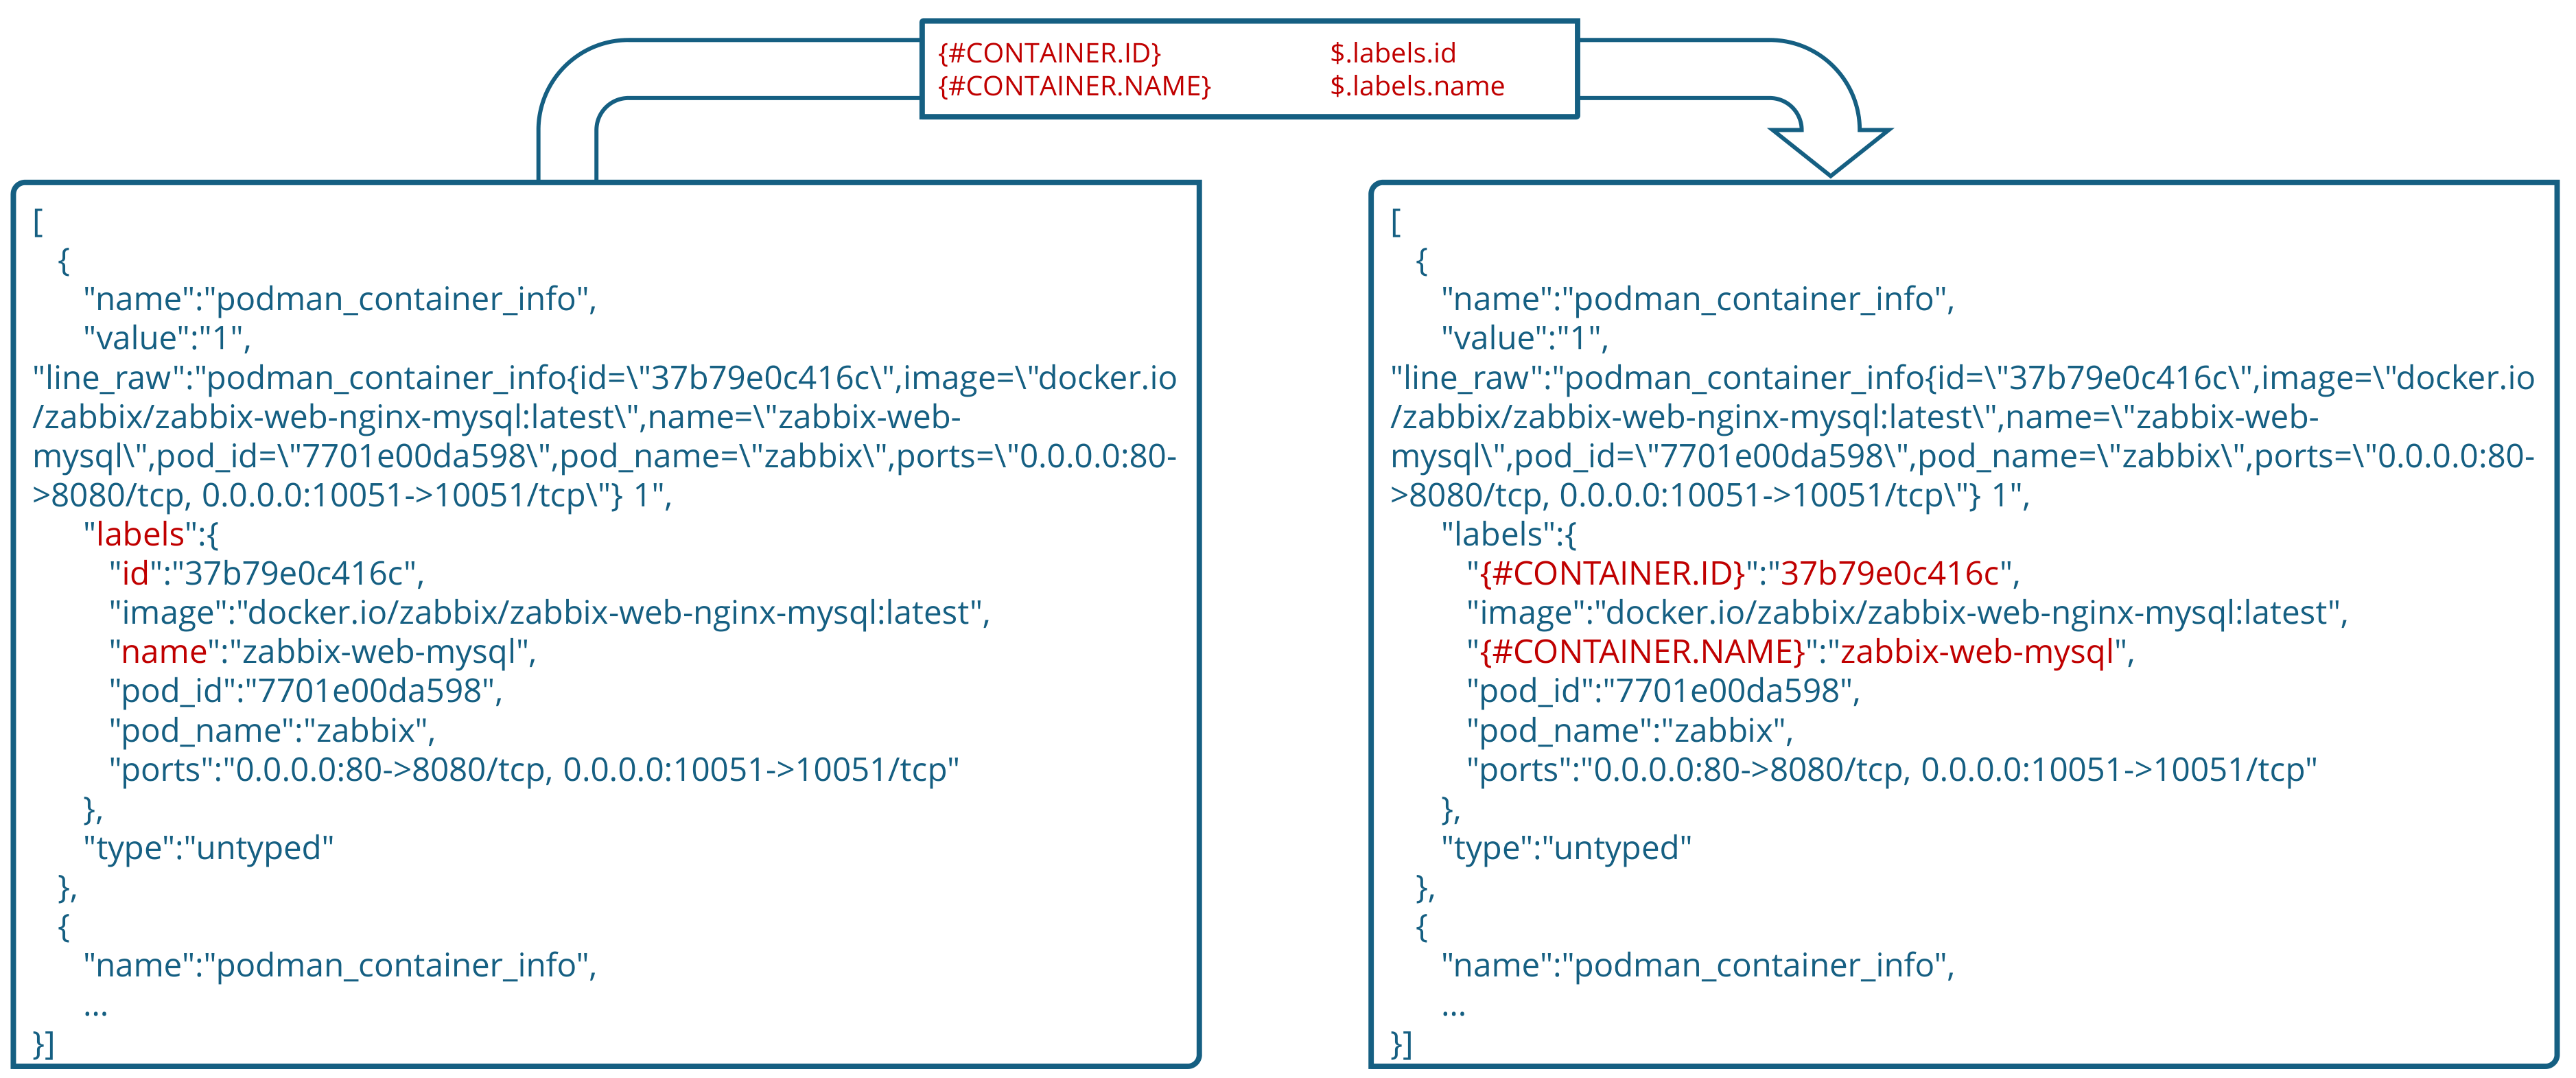
  ▪ {#CONTAINER.ID}        $.labels.id
  ▪ {#CONTAINER.NAME}      $.labels.name
Fig 1. Discovery rule: Container discovery
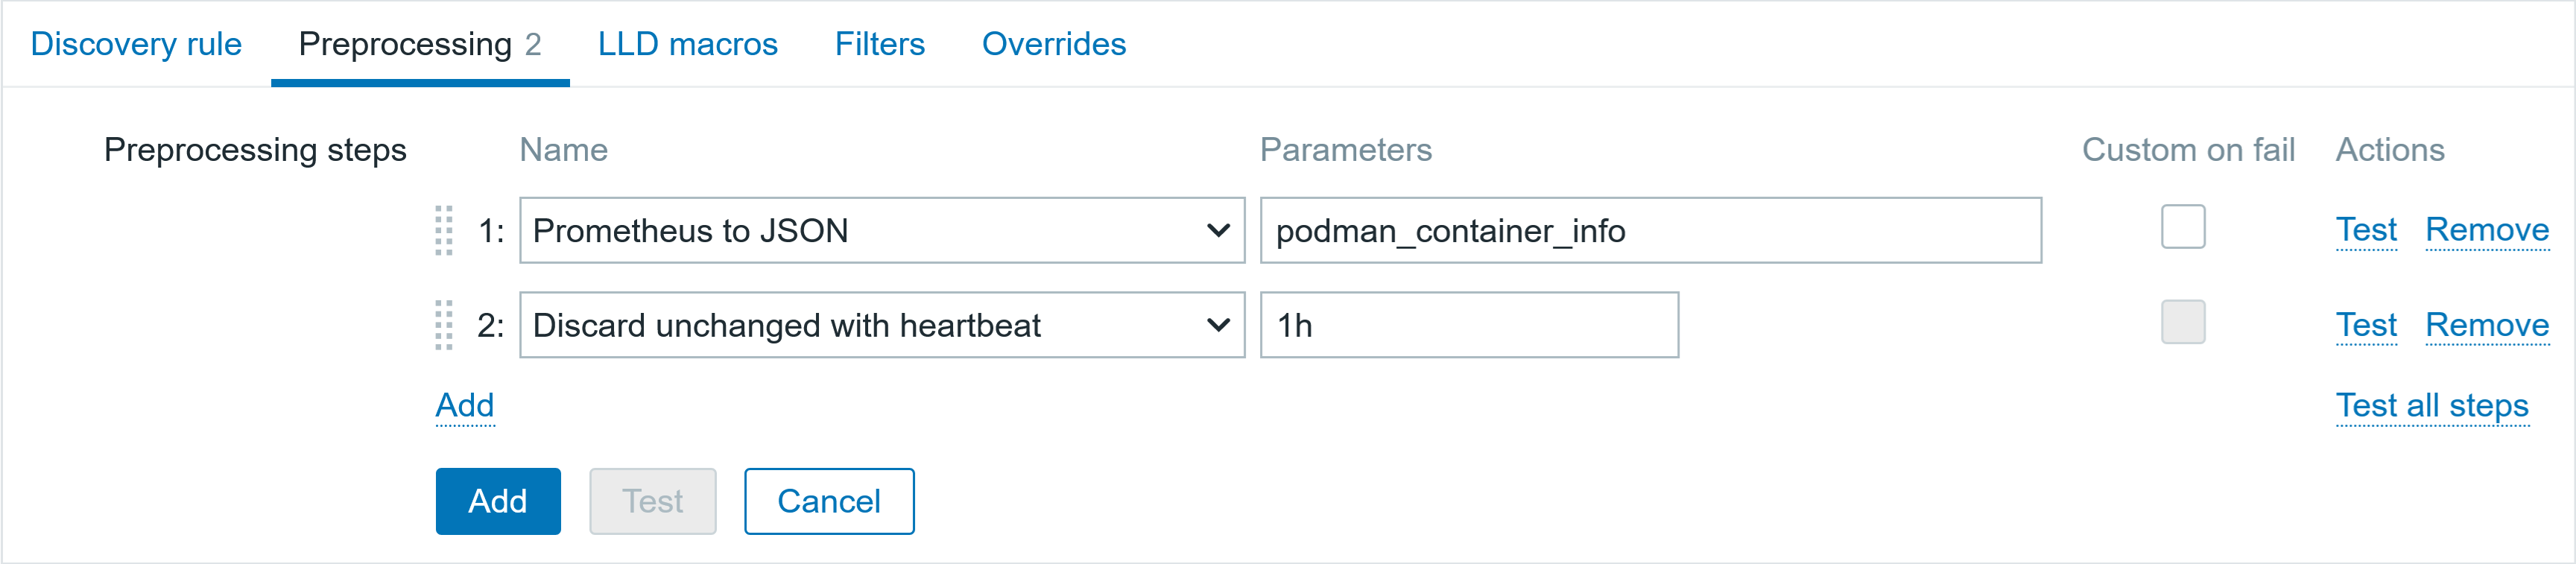
Fig 2. Discovery rule: Container discovery preprocessing tab
Fig 3. Discovery rule: Container discovery LLD macros tab

Next, different dependent item prototypes are created in this container discovery rule. As the Prometheus Podman exporter provides a lot of different metrics about the containers, I will create multiple such items: state, health, creation date, input/output network traffic information, and so on. So, check out what metrics can be acquired and use what is relevant for you.

You can also add a description of each item prototype. I am interested only in metrics with the discovered container ID macros, and I am not interested in what values are for the other fields, such as pod_id, pod_name, so I use ~”.*”, which matches any value. I will show the item prototype configuration screenshots of one of the item prototypes.

These item prototypes are similar to each other, with some minor differences, such as Prometheus patterns, or in some cases, with a different master item (item prototype as master item).

Fig 4. Discovery rule preprocessing step: Prometheus to JSON with pattern podman_container_info
Fig 5. Discovery rule LLD macros: assigning relevant JSONPATH to LLD macros

Creating a template discovery rule: Item prototypes

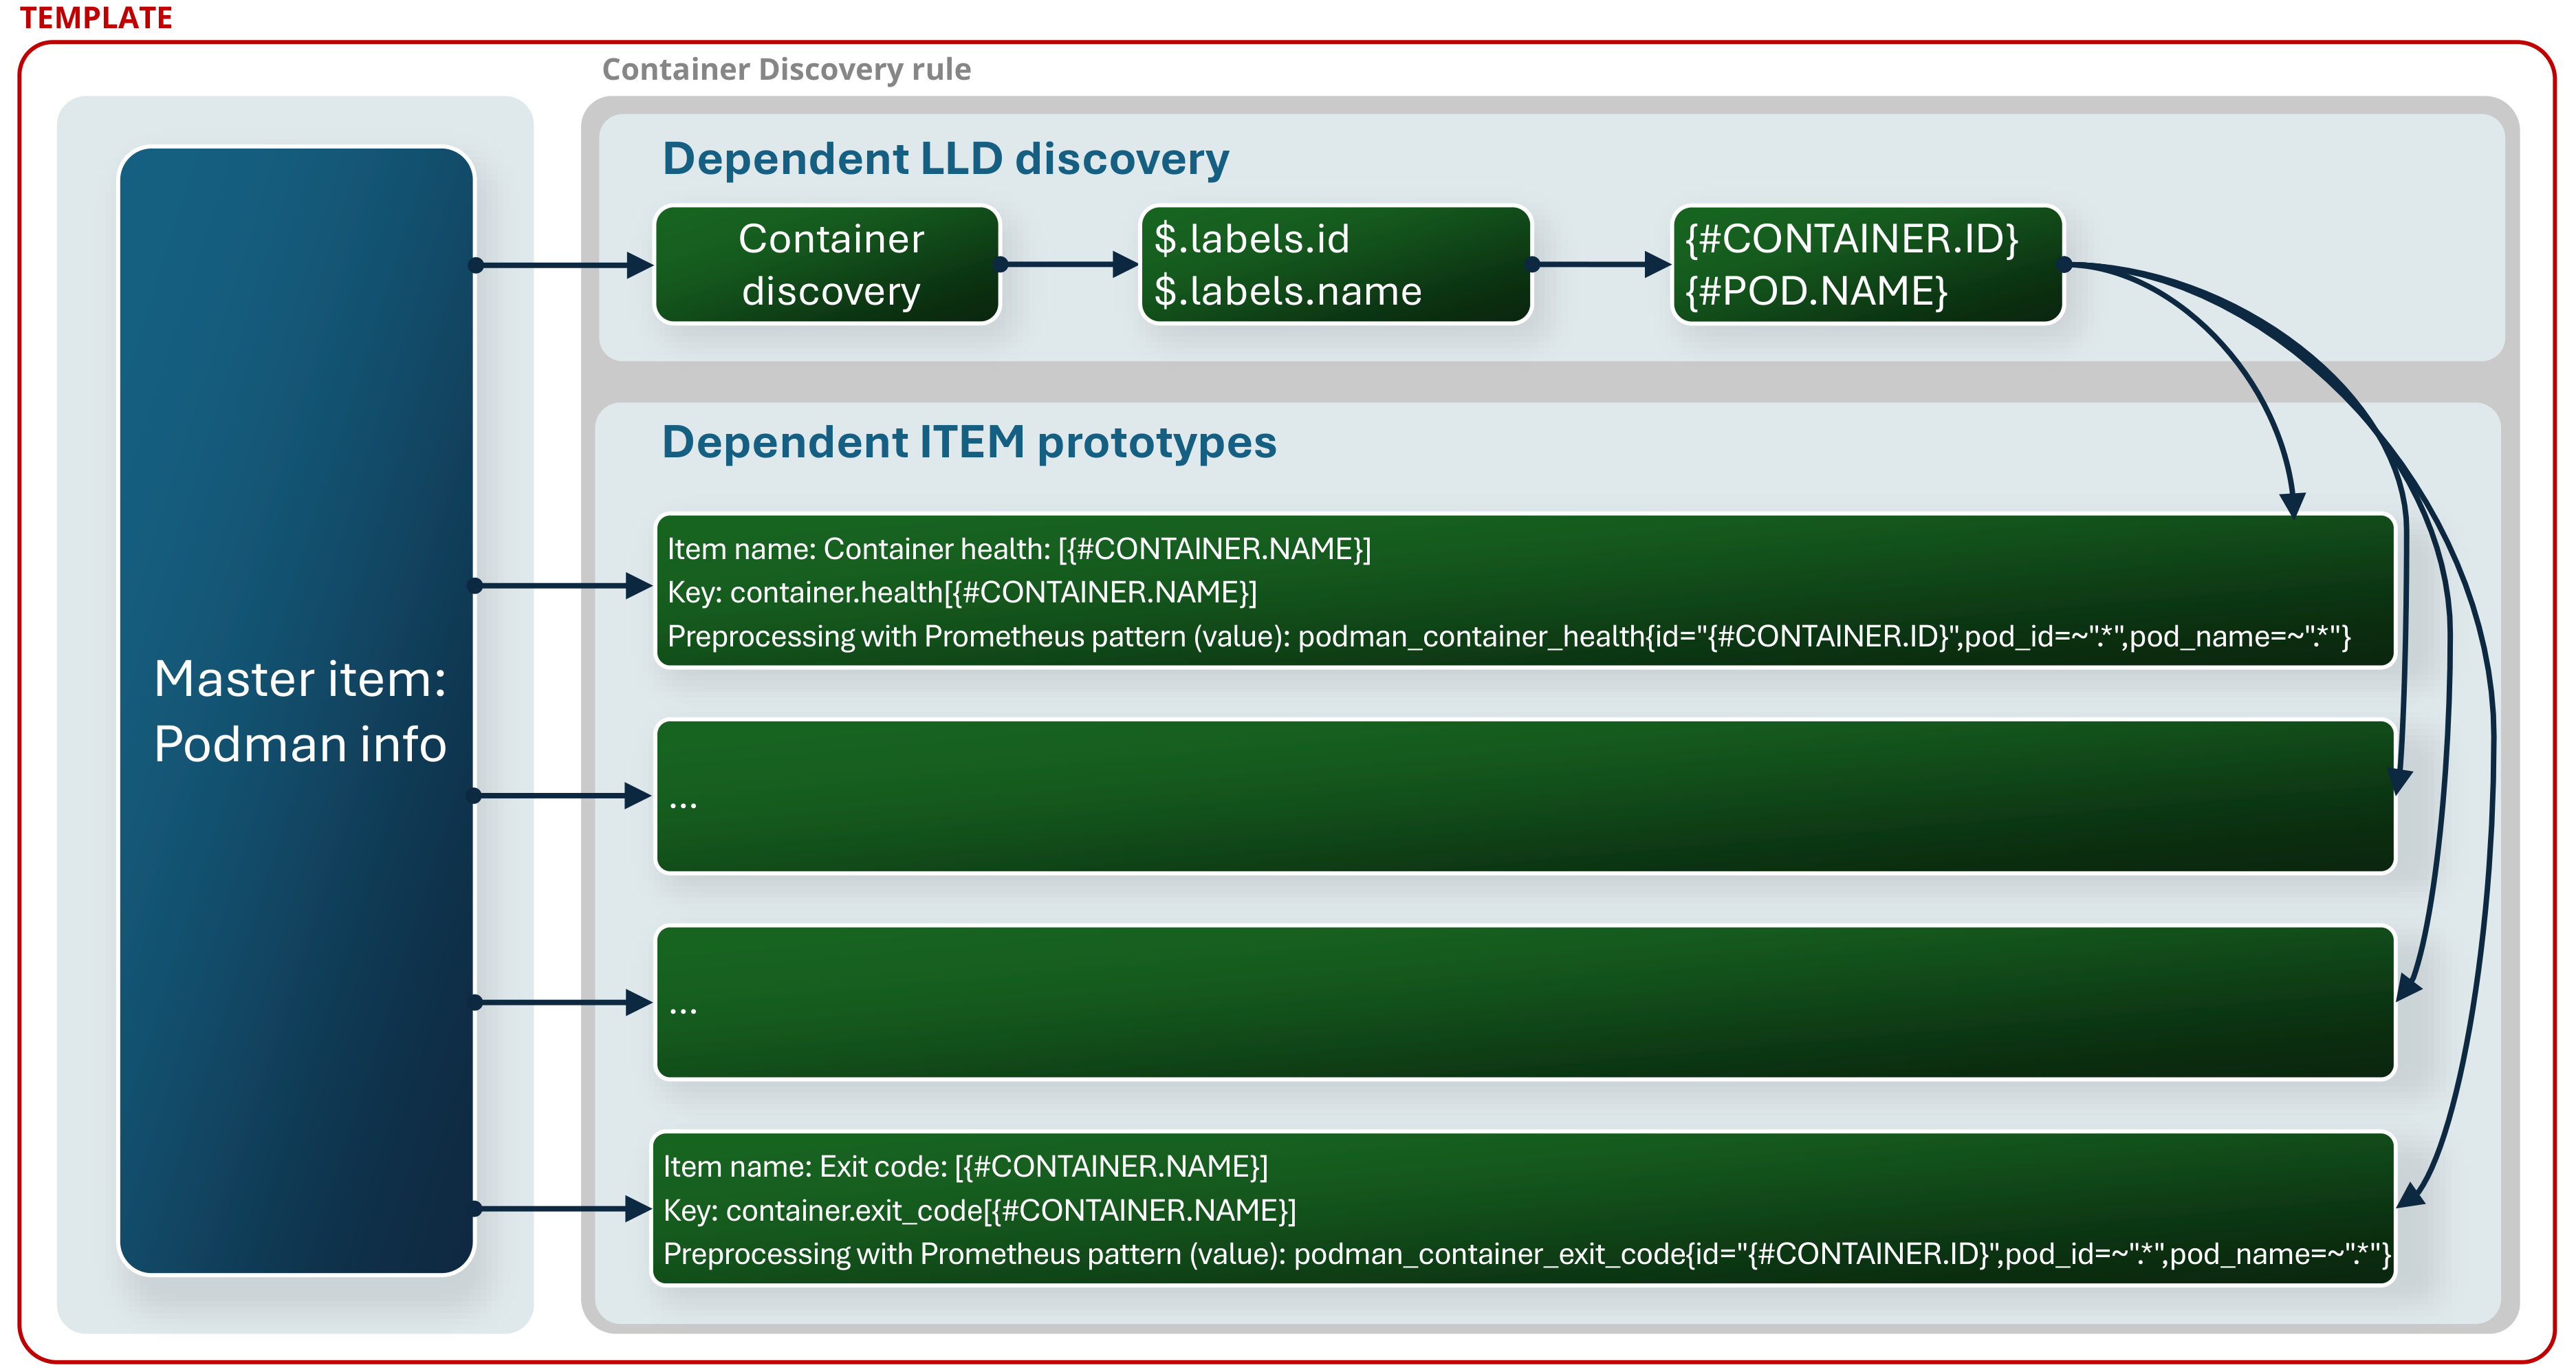
After the containers have been discovered, we have to create item prototypes. These prototypes will also be dependent item prototypes and will use the same item as the discovery rule: Podman info. Prometheus Podman exported returns a lot more metrics for the containers than it did for the pods.

You can get container metrics such as container health, state, creation date, disk read/write, memory usage, network usage, and more. In this blog post, I have added most of them, so check what metrics are relevant to your monitoring needs and start monitoring.

Fig 6. Low-level discovery rule and item prototypes based on the same item.

The screenshots of the item prototype is shown below.

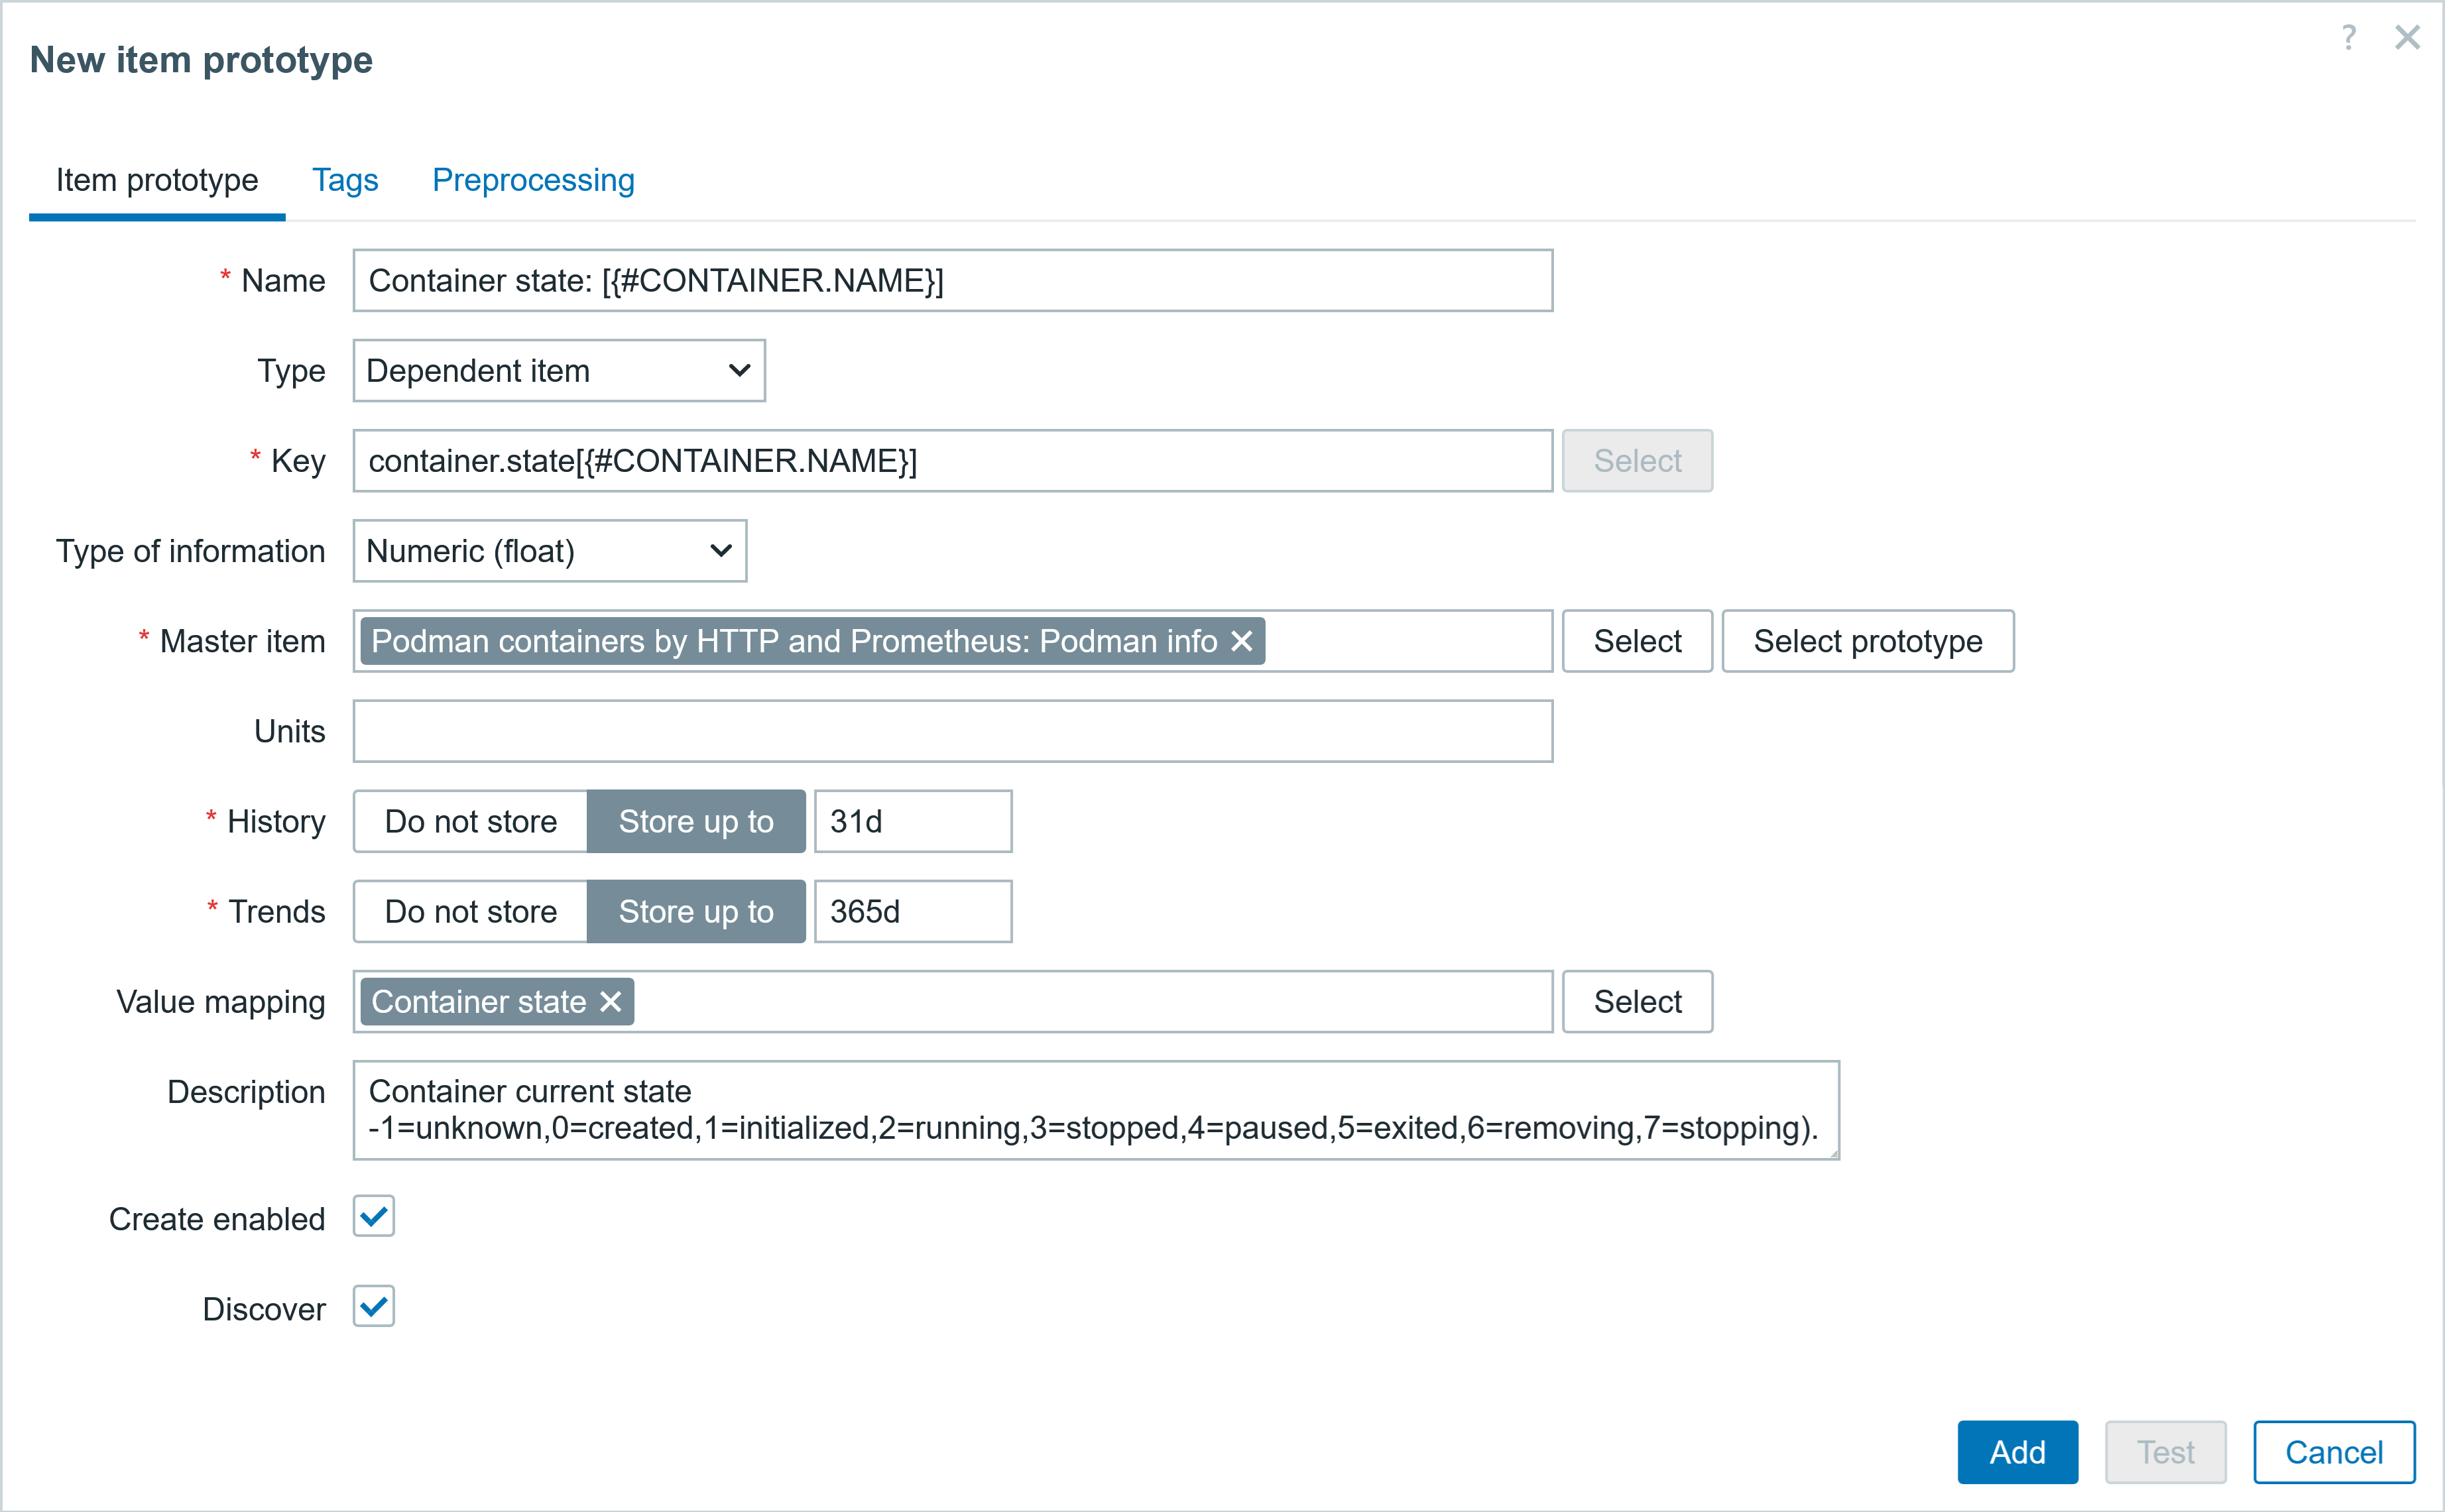
Fig 7. Container state item prototype tab
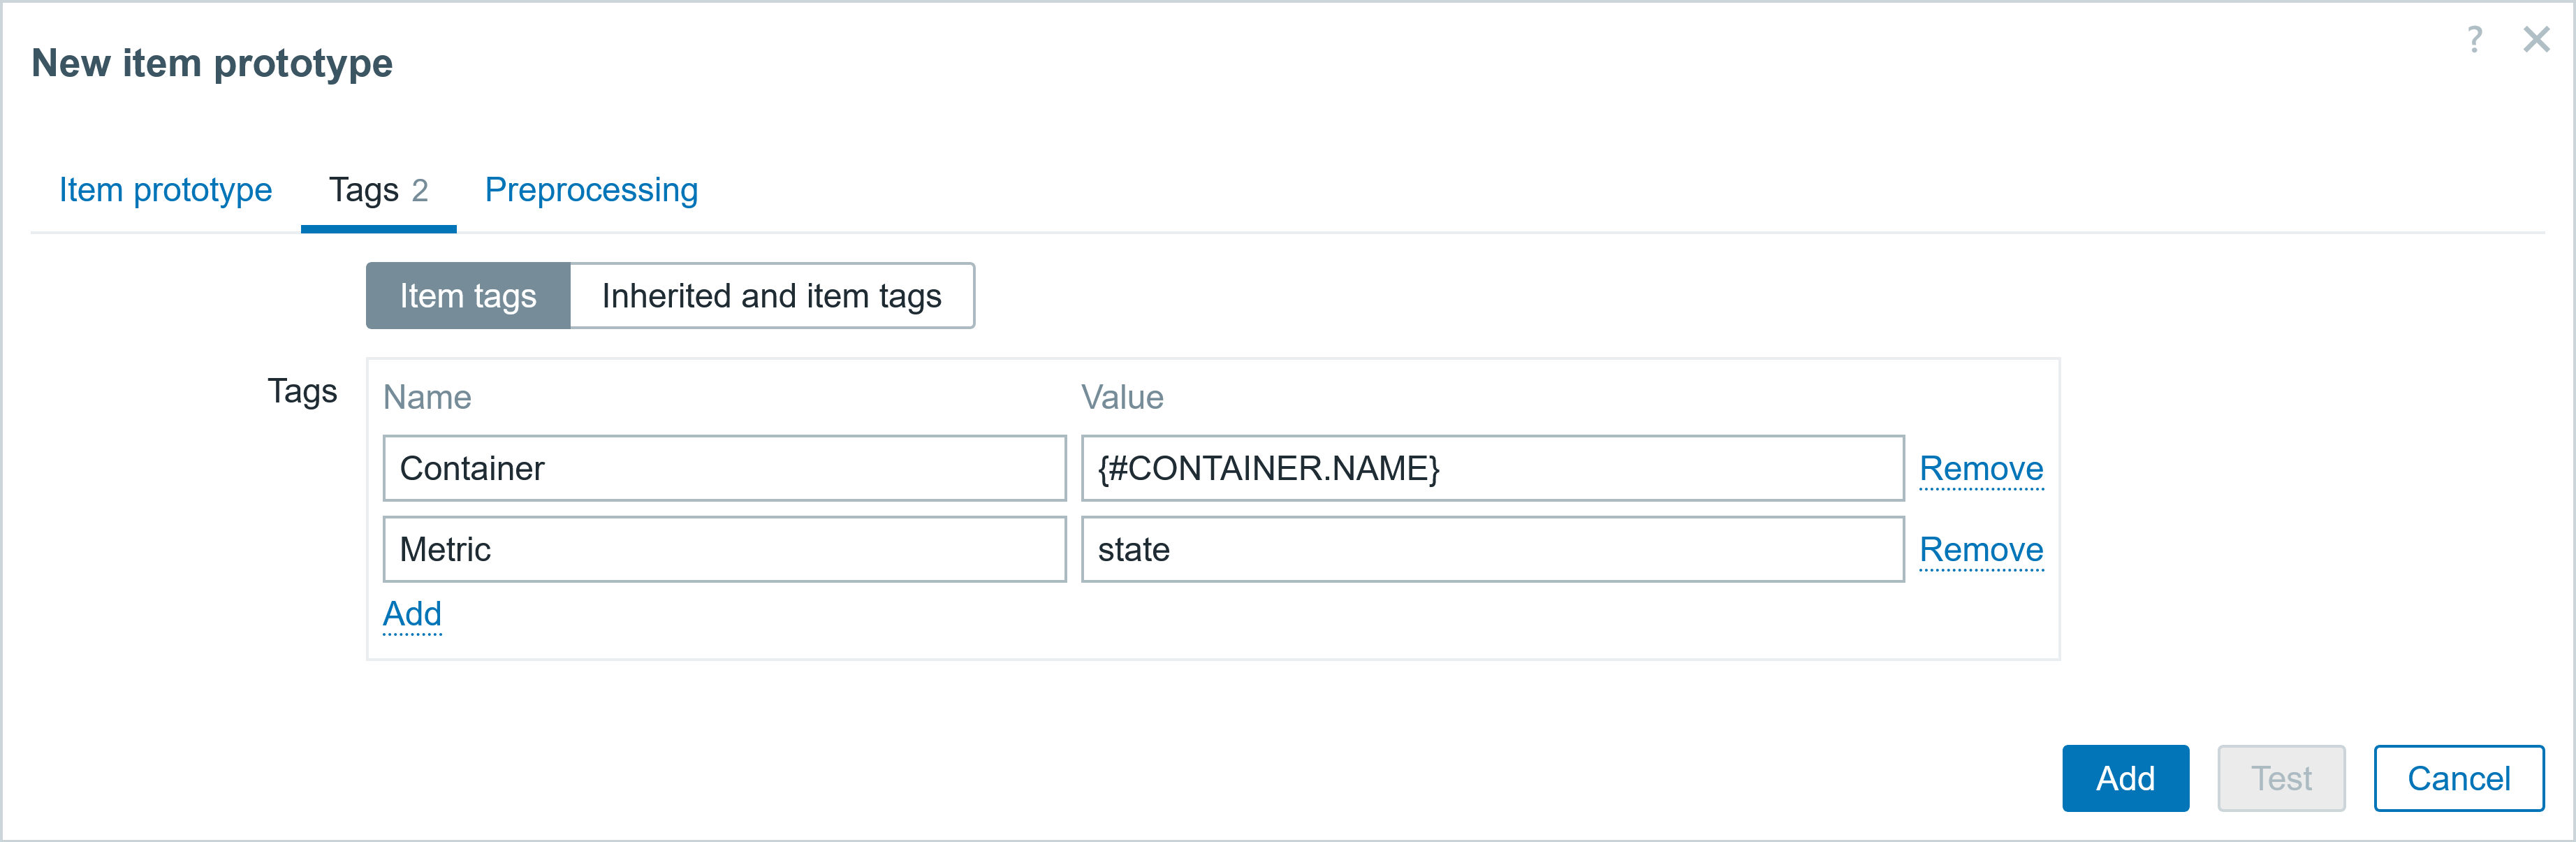
Fig 8. Container state item prototype tag tab
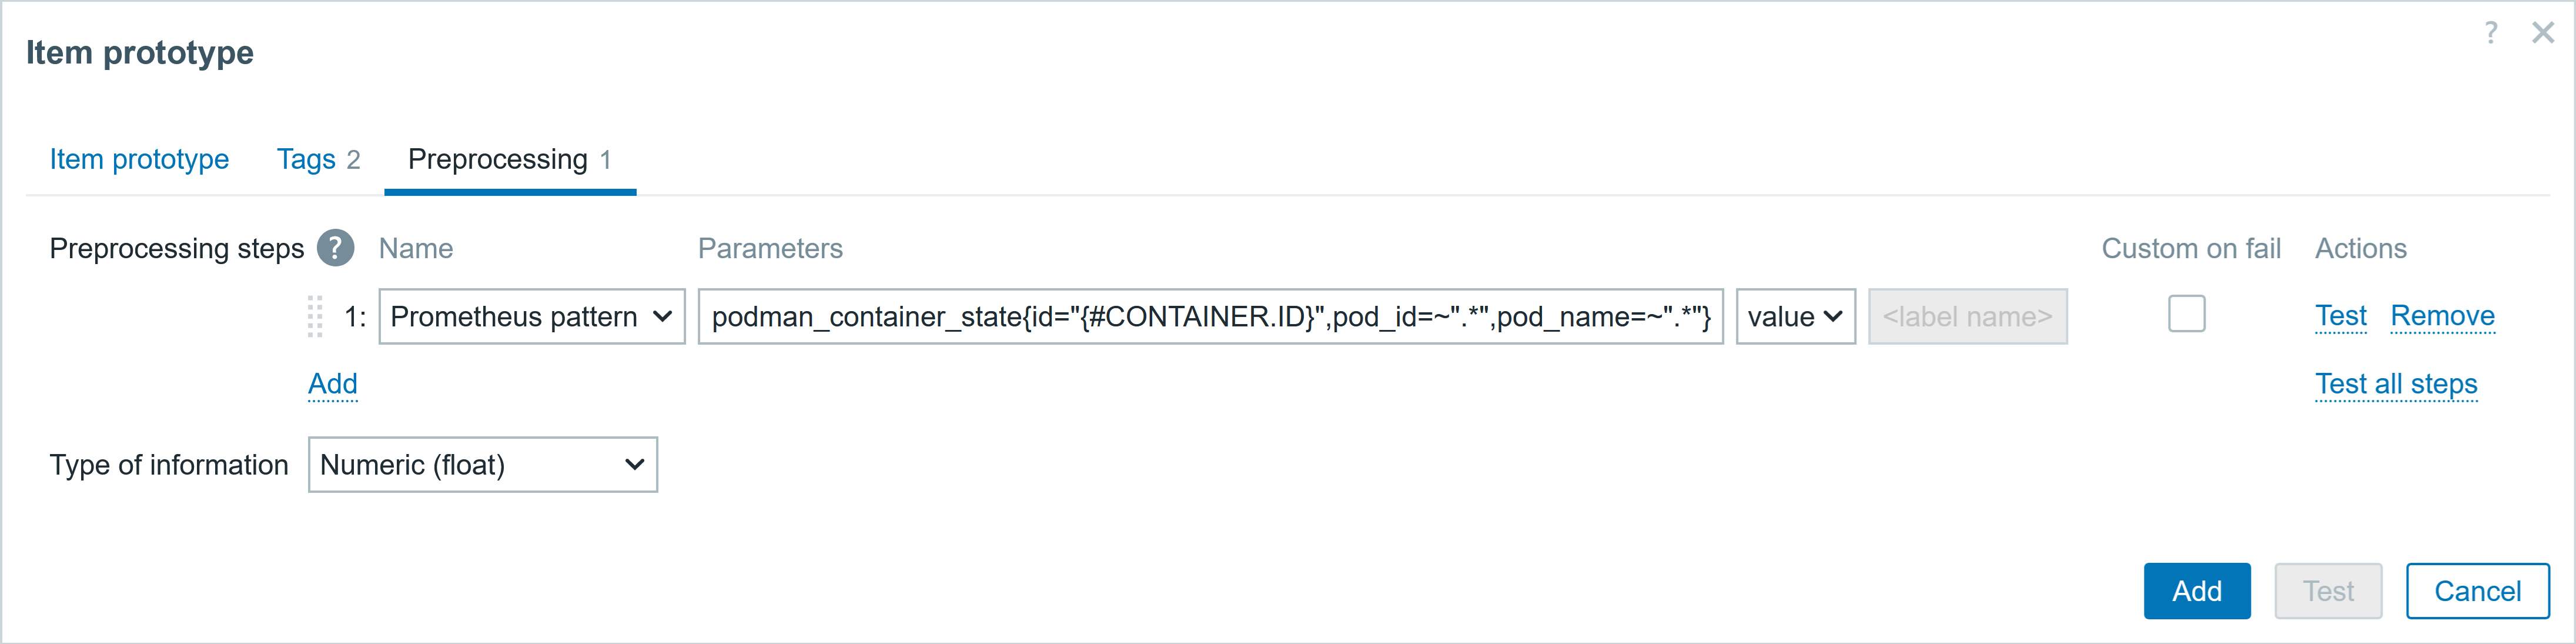
Fig 9. Container state item prototype preprocessing tab

Remember, you can also test these item prototypes in the preprocessing step – just copy the Prometheus exporter data and set the relevant macro to value you want to check.

The configuration parameters of the item prototypes are shown below. There are a lot of metrics you can monitor, but remember to monitor what is relevant and necessary for you.

Template: Podman containers by HTTP and Prometheus; Discovery rule: Container discovery

● Item prototype #1
  ▪ Name: 		Container health: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.health[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (float)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 
♦ Tags (name:value) 	
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:health		
♯ Preprocessing
  ▪ Prometheus pattern 	podman_container_health{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #2
  ▪ Name: 		Container state: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.state[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (float)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		
♦ Tags (name:value)  			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:state		
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_state{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #3
  ▪ Name: 		Created at: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.created[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		unixtime
♦ Tags (name:value) 		
  ▪ Container:{#CONTAINER.NAME}	
  ▪Metric:created		
♯ Preprocessing
  ▪ Prometheus pattern 	podman_container_created_seconds{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #4
  ▪ Name: 		Disk read per second: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.disk.read[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		B
♦ Tags (name:value) 	
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:disk_read		
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_block_output_total{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value
  ▪ Change per second

● Item prototype #5
  ▪ Name: 		Disk write per second: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.disk.write[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		B
♦ Tags (name:value) 	
  ▪ Container:{#CONTAINER.NAME}	 
  ▪ Metric:disk_write		
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_block_input_total{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value
  ▪ Change per second

● Item prototype #6
  ▪ Name: 		Exit code: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.exit_code[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (float)
    ▪ Master item	Podman containers by HTTP and Prometheus: Podman info
▪ Units: 			
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:exit_code	
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_exit_code{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #7
  ▪ Name: 		Image tags: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.image.tags[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Character
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 			
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:tag
♯ Preprocessing
▪ Prometheus pattern podman_container_info{id="{#CONTAINER.ID}",image=~".*",name=~".*",pod_id=~".*",pod_name=~".*",ports=~".*"} label image
  ▪ Regular expression	\.*(\/.\w.*)	\1

● Item prototype #8
  ▪ Name: 		Memory usage: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.mem[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		B
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:mem		
♯ Preprocessing
  ▪ Prometheus pattern podman_container_mem_usage_bytes{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #9
  ▪ Name: 		Network input dropped: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.net.in.drop[{#CONTAINER.NAME}]
  ▪ Type of inf: Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		packets
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:net_in_drop		
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_net_input_dropped_total{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #10
  ▪ Name: 		Network input errors: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.net.in.errors[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:net_in_err		
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_net_input_errors_total{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #11
  ▪ Name: 		Network input total: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.net.in.total[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		B
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:net_in_tot
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_net_input_total{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #12
  ▪ Name: 		Network input per second: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.net.in.change[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (float)
  ▪ Master item		prototype - Network input total: [{#CONTAINER.NAME}] 
  ▪ Units: 		Bps
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:net_in_change
♯ Preprocessing
  ▪ Change per second

● Item prototype #13
  ▪ Name: 		Network output dropped: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.net.out.drop[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:net_out_drop	
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_net_output_dropped_total{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #14
  ▪ Name: 		Network output errors: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.net.out.errors[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:net_out_err	
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_net_output_errors_total{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #15
  ▪ Name: 		Network output total: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.net.out.total[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		B
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:net_out_tot	
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_net_output_total{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #16
  ▪ Name: 		Network output per second: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.net.out.change[{#CONTAINER.NAME}]
  ▪ Type of inf: 	Numeric (float)
  ▪ Master item		prototype - Network output total: [{#CONTAINER.NAME}]
  ▪ Units: 		Bps
♦ Tags 			 
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:net_out_change
♯ Preprocessing
  ▪ Name			Change per second

● Item prototype #17
  ▪ Name: 		Rootfs size: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.rootfs.size[{#CONTAINER.NAME}]
  ▪ Type of inf: Numeric (unsigned)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		B
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:rootfs
♯ Preprocessing
  ▪ Prometheus pattern	podman_container_rootfs_size_bytes{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

● Item prototype #18
  ▪ Name: 		Total system CPU time: [{#CONTAINER.NAME}]
  ▪ Type 		Dependent item
  ▪ Key: 		container.cpu.time
  ▪ Type of inf: 	Numeric (float)
  ▪ Master item		Podman containers by HTTP and Prometheus: Podman info
  ▪ Units: 		s
♦ Tags 			
  ▪ Container:{#CONTAINER.NAME}	
  ▪ Metric:sys_time
♯ Preprocessing
  ▪ Prometheus pattern: podman_container_cpu_system_seconds_total{id="{#CONTAINER.ID}",pod_id=~".*",pod_name=~".*"} value

Creating a template discovery rule: Trigger prototype

I have created a user macro {$CONTAINER.RUNNING.STATE} on the template with a value of 2, which corresponds to the containers running state. After that, create a trigger prototype to check if the container is in different state other than running.

Template: Podman containers by HTTP and Prometheus; Discovery rule: Container discovery

◘ Trigger prototypes
  ▪ Name:               Container [{#CONTAINER.NAME}] state has changed from running
  ▪ Severity:           Warning
  ▪ Expression:         last(/Podman containers by HTTP and Prometheus/container.state[{#CONTAINER.NAME}])<>{$CONTAINER.RUNNING.STATE}
  ▪ PROBLEM event generation mode: Single
  ▪ OK event closes: All problems

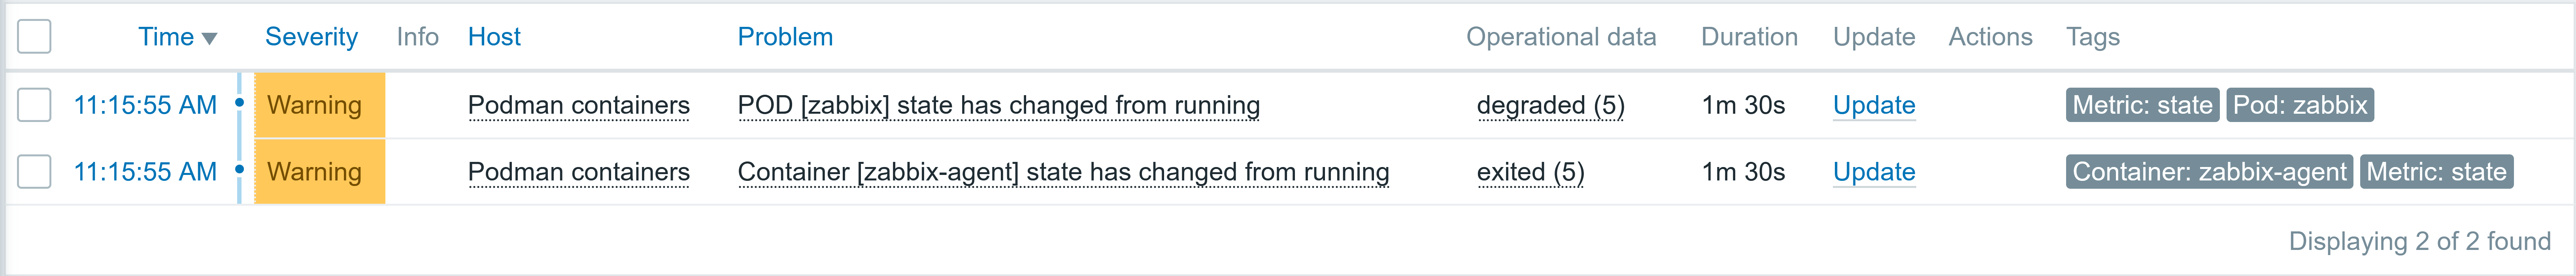
So, once all of this is done, and some container status changes from running and or pod status also changes from running, you will get a problem event.

Fig 10. Generated problem events when the podman pod and container change states.

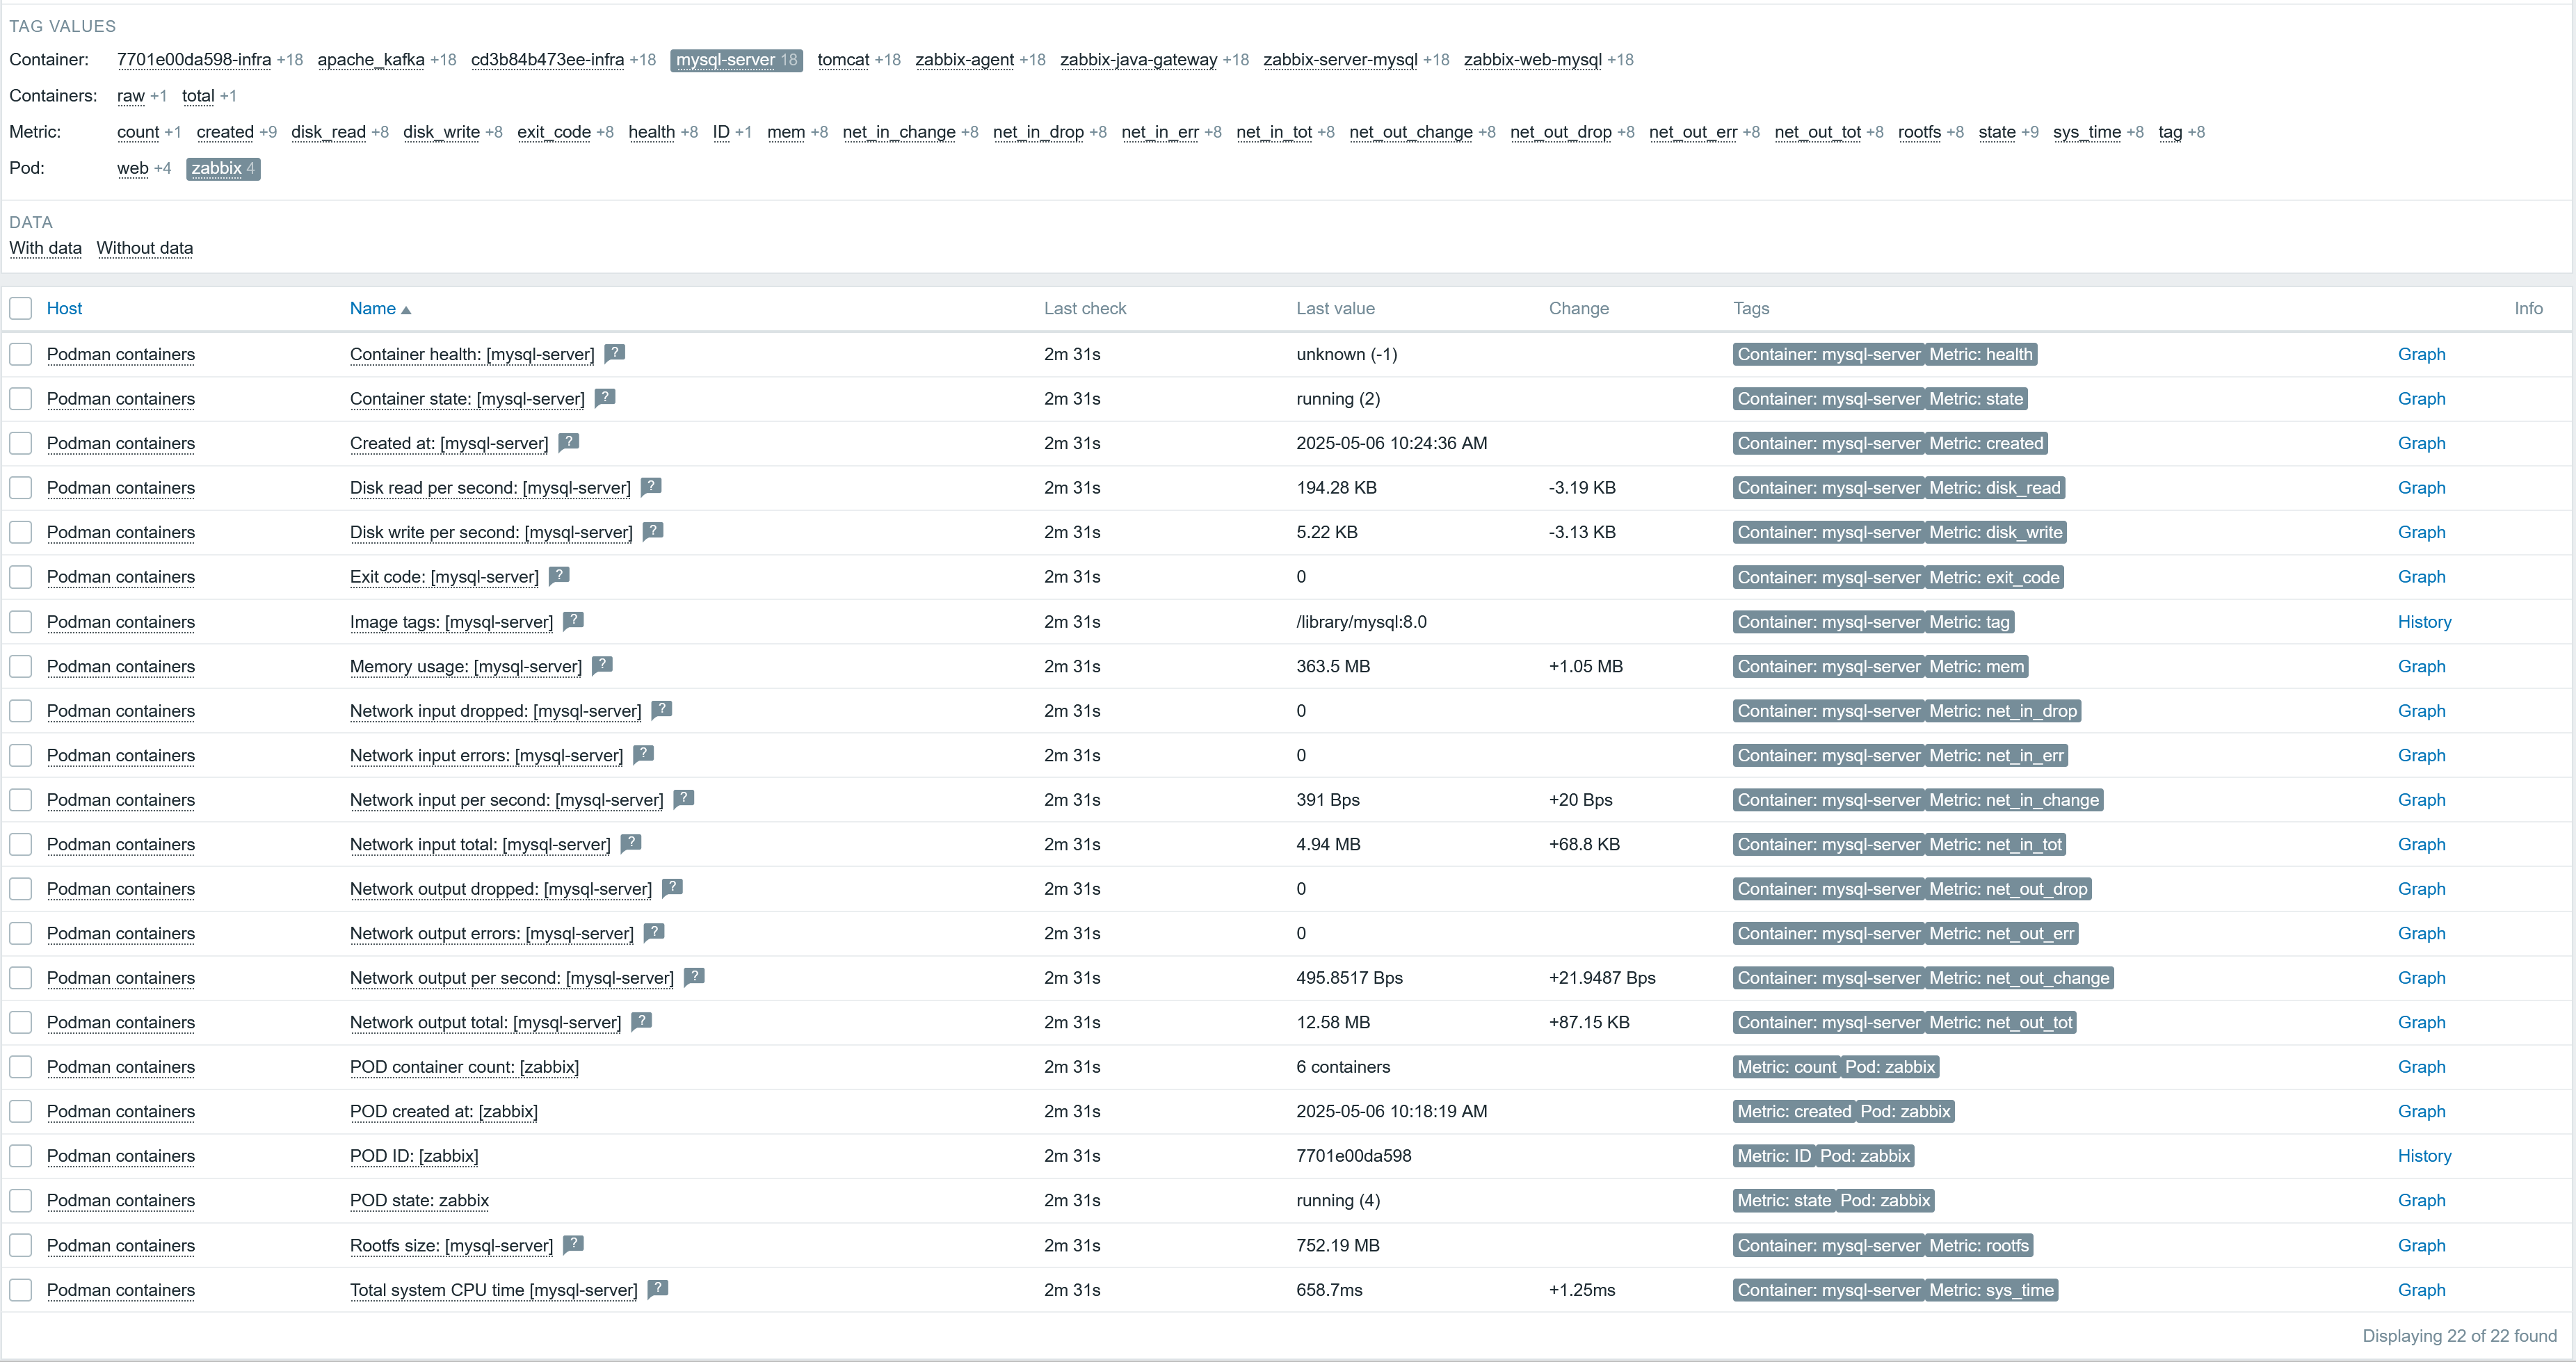
Technically, I could also create a trigger for container health; however, as all of the received container values for me are -1 (meaning unknown) it makes little sense to make a trigger that will fire right away. You can also add additional item/trigger prototypes in the template. If everything is set up as expected, you should see something like the screenshot below after the LLD rule execution.

Fig 11. Example of the mysql-server container and zabbix pod item values.

Summary

Now, you can monitor both Podman pods and containers using both blog posts of this series. We used the same template item for both the container LLD and item prototypes from the first part of this post.

The post Podman Container Monitoring with Prometheus Exporter, part 2 appeared first on Zabbix Blog.

Celebrating 11 years of Project Galileo’s global impact

Post Syndicated from Jocelyn Woolbright original https://blog.cloudflare.com/celebrating-11-years-of-project-galileo-global-impact/

June 2025 marks the 11th anniversary of Project Galileo, Cloudflare’s initiative to provide free cybersecurity protection to vulnerable organizations working in the public interest around the world. From independent media and human rights groups to community activists, Project Galileo supports those often targeted for their essential work in human rights, civil society, and democracy building.

A lot has changed since we marked the 10th anniversary of Project Galileo. Yet, our commitment remains the same: help ensure that organizations doing critical work in human rights have access to the tools they need to stay online.  We believe that organizations, no matter where they are in the world, deserve reliable, accessible protection to continue their important work without disruption.

For our 11th anniversary, we’re excited to share several updates including:

  • An interactive Cloudflare Radar report providing insights into the cyber threats faced by at-risk public interest organizations protected under the project. 

  • An expanded commitment to digital rights in the Asia-Pacific region with two new Project Galileo partners.

  • New stories from organizations protected by Project Galileo working on the frontlines of civil society, human rights, and journalism from around the world.


Tracking and reporting on cyberattacks with the Project Galileo 11th anniversary Radar report 

To mark Project Galileo’s 11th anniversary, we’ve published a new Radar report that shares data on cyberattacks targeting organizations protected by the program. It provides insights into the types of threats these groups face, with the goal of better supporting researchers, civil society, and vulnerable groups by promoting the best cybersecurity practices. Key insights include:

  • Our data indicates a growing trend in DDoS attacks against these organizations, becoming more common than attempts to exploit traditional web application vulnerabilities.

  • Between May 1, 2024, to March 31, 2025, Cloudflare blocked 108.9 billion cyber threats against organizations protected under Project Galileo. This is an average of nearly 325.2 million cyber attacks per day over the 11-month period, and a 241% increase from our 2024 Radar report. 

  • Journalists and news organizations experienced the highest volume of attacks, with over 97 billion requests blocked as potential threats across 315 different organizations. The peak attack traffic was recorded on September 28, 2024. Ranked second was the Human Rights/Civil Society Organizations category, which saw 8.9 billion requests blocked, with peak attack activity occurring on October 8, 2024.

  • Cloudflare onboarded the Belarusian Investigative Center, an independent journalism organization, on September 27, 2024, while it was already under attack. A major application-layer DDoS attack followed on September 28, generating over 28 billion requests in a single day. 

  • Many of the targets were investigative journalism outlets operating in regions under government pressure (such as Russia and Belarus), as well as NGOs focused on combating racism and extremism, and defending workers’ rights.

  • Tech4Peace, a human rights organization focused on digital rights, was targeted by a 12-day attack beginning March 10, 2025, that delivered over 2.7 billion requests. The attack saw prolonged, lower-intensity attacks and short, high-intensity bursts. This deliberate variation in tactics reveals a coordinated approach, showing how attackers adapted their methods throughout the attack.

The full Radar report includes additional information on public interest organizations, human and civil rights groups, environmental organizations, and those involved in disaster and humanitarian relief. The dashboard also serves as a valuable resource for policymakers, researchers, and advocates working to protect public interest organizations worldwide.

Global partners are the key to Project Galileo’s continued growth

Partnerships are core to Project Galileo success. We rely on 56 trusted civil society organizations around the world to help us identify and support groups who could benefit from our protection. With our partners’ help, we’re expanding our reach to provide tools to communities that need protection the most. Today, we’re proud to welcome two new partners to Project Galileo who are championing digital rights, open technologies, and civil society in Asia and around the world. 


EngageMedia is a nonprofit organization that brings together advocacy, media, and technology to promote digital rights, open and secure technology, and social issue documentaries. Based in the Asia-Pacific region, EngageMedia collaborates with changemakers and grassroots communities to protect human rights, democracy, and the environment.

As part of our partnership, Cloudflare participated in a 2025 Tech Camp for Human Rights Defenders hosted by EngageMedia, which brought together around 40 activist-technologists from across Asia-Pacific. Among other things, the camp focused on building practical skills in digital safety and website resilience against online threats. Cloudflare presented on common attack vectors targeting nonprofits and human rights groups, such as DDoS attacks, phishing, and website defacement, and shared how Project Galileo helps organizations mitigate these risks. We also discussed how to better promote digital security tools to vulnerable groups. The camp was a valuable opportunity for us to listen and learn from organizations on the front lines, offering insights that continue to shape our approach to building effective, community-driven security solutions.


Founded in 2014 by leaders of Taiwan’s open tech communities, the Open Culture Foundation (OCF) supports efforts to protect digital rights, promote civic tech, and foster open collaboration between government, civil society, and the tech community. Through our partnership, we aim to support more than 34 local civil society organizations in Taiwan by providing training and workshops to help them manage their website infrastructure, address vulnerabilities such as DDoS attacks, and conduct ongoing research to tackle the security challenges these communities face.

Stories from the field  

We continue to be inspired by the amazing work and dedication of the organizations that participate in Project Galileo. Helping protect these organizations and allowing them to focus on their work is a fundamental part of helping build a better Internet. Here are some of their stories:

  • Fair Future Foundation (Indonesia): non-profit that provides health, education, and access to essential resources like clean water and electricity in ultra-rural Southeast Asia. 

  • Youth Initiative for Human Rights (Serbia): regional NGO network promoting human rights, youth activism, and reconciliation in the Balkans.

  • Belarusian Investigative Center (Belarus): media organization that conducts in-depth investigations into corruption, sanctions evasion, and disinformation in Belarus and neighboring regions. 

  • The Greenpeace Canada Education Fund (GCEF) (Canada): non-profit that conducts research, investigations, and public education on climate change, biodiversity, and environmental justice. 

  • Insight Crime (LATAM): nonprofit think tank and media organization that investigates and analyzes organized crime and citizen security in Latin America and the Caribbean. 

  • Diez.md (Moldova): youth-focused Moldovan news platform offering content in Romanian and Russian on topics like education, culture, social issues, election monitoring and news. 

  • Engage Media (APAC): nonprofit dedicated to defending digital rights and supporting advocates for human rights, democracy, and environmental sustainability across the Asia-Pacific. 

  • Pussy Riot (Europe): a global feminist art and activist collective using art, performance, and direct action to challenge authoritarianism and human rights violations. 

  • Immigrant Legal Resource Center (United States): nonprofit that works to advance immigrant rights by offering legal training, developing educational materials, advocating for fair policies, and supporting community-based organizations.

  • 5wf Foundation (Netherlands): wildlife conservation non-profit that supports front-line conservation teams globally by providing equipment to protect threatened species and ecosystems.

These case studies offer a window into the diverse, global nature of the threats these groups face and the vital role cybersecurity plays in enabling them to stay secure online. Check out their stories and more: cloudflare.com/project-galileo-case-studies/

Continuing our support of vulnerable groups around the world 

In 2025, many of our Project Galileo partners have faced significant funding cuts, affecting their operations and their ability to support communities, defend human rights, and champion democratic values. Ensuring continued support for those services, despite financial and logistical challenges, is more important than ever. We’re thankful to our civil society partners who continue to assist us in identifying groups that need our support. Together, we’re working toward a more secure, resilient, and open Internet for all. To learn more about Project Galileo and how it supports at-risk organizations worldwide, visit cloudflare.com/galileo.

Google has New NVIDIA RTX Pro 6000 8-GPU Instances with AMD EPYC 9005 CPUs

Post Syndicated from Cliff Robinson original https://www.servethehome.com/google-has-new-nvidia-rtx-pro-6000-8-gpu-instances-with-amd-epyc-9005-cpus/

The new Google G4 instances house eight NVIDIA RTX Pro 6000 GPUs, combining for 768GB of memory, along with two AMD EPYC Turin CPUs

The post Google has New NVIDIA RTX Pro 6000 8-GPU Instances with AMD EPYC 9005 CPUs appeared first on ServeTheHome.

[$] LWN.net Weekly Edition for June 12, 2025

Post Syndicated from corbet original https://lwn.net/Articles/1023924/

Inside this week’s LWN.net Weekly Edition:

  • Front: Nyxt; Cyber Resilience Act; Unwanted file descriptors; Core-dump API; 6.16 Merge window; Uniprocessor configurations; Smatch; FUSE zero-copy; iov_iter; Fedora documentation.
  • Briefs: Android tracking; /e/OS 3.0; FreeBSD laptops; Ubuntu X11 support; Netdev 0x19; OIN anniversary; Quotes; …
  • Announcements: Newsletters, conferences, security updates, patches, and more.

The complete stream processing journey on FlinkSQL

Post Syndicated from Grab Tech original https://engineering.grab.com/the-complete-stream-processing-journey-on-flinksql

Introduction

In the fast-paced world of data analytics, real-time processing has become a necessity. Modern businesses require insights not just quickly, but in real-time to make informed decisions and stay ahead of the competition. Apache Flink has emerged as a powerful tool in this domain, offering state-of-the-art stream processing capabilities. In this blog, we introduce our FlinkSQL interactive solution in accompanying productionising automation, and enhancing our users’ stream processing development journey.

Preface

Last year, we introduced Zeppelin notebooks for Flink, as detailed in our previous post Rethinking Stream Processing: Data Exploration in an effort to enhance data exploration for downstream data users. However, as our use cases evolved over time, we quickly hit a few technical roadblocks.

Zeppelin notebook source code is maintained by a community separate from Flink’s community. As of writing, the latest Flink version supported is 1.17, whilst the latest Flink is already on version 1.20. This discrepancy in version support hinders our Flink upgrading efforts.

Cluster start up time

Our design to spin up a Zeppelin cluster per user on demand invokes a cold start delay, taking roughly around 5 minutes for the notebook to be ready. This delay is not suitable for use cases that require quick insights from production data. We quickly noticed that the user uptake of this solution was not as high as we expected.

Integration challenges

Whilst Zeppelin notebooks were useful for serving individual developers, we experienced difficulty integrating it with other internal platforms. We designed Zeppelin to empower solo data explorers, but other internal platforms like dashboards or automated pipelines needed a way to aggregate data from Kafka and Zeppelin just couldn’t keep up. The notebook setup was too isolated, requiring a workaround to share insights or plug into existing tools. For instance, if a team wanted to pull aggregated real-time metrics into a monitoring system, they had to export data manually, which is far from seamless access that we aimed for.

Introducing FlinkSQL interactive

With those considerations in mind, we decided to swap out our Zeppelin cluster with a shared FlinkSQL gateway cluster. We simplified our solution by removing some features our notebooks offered, focusing only on features that promote data democratisation.

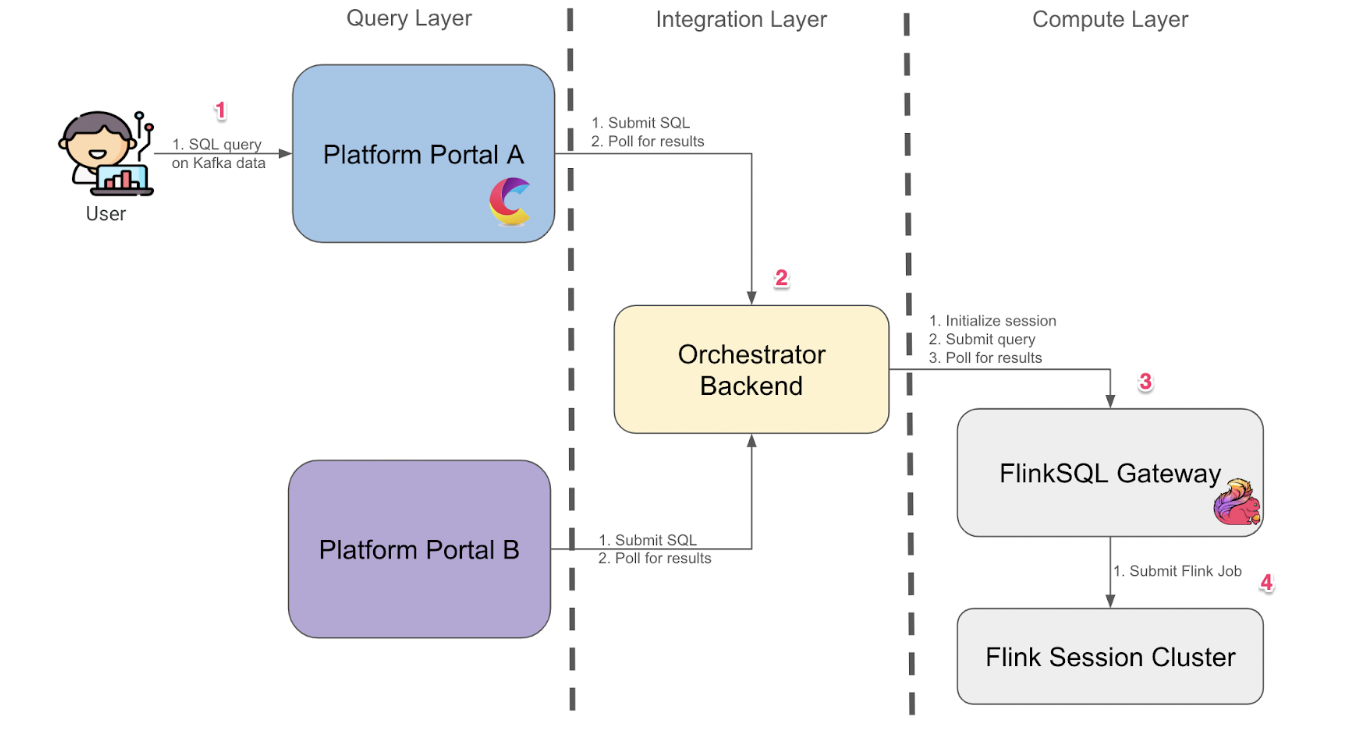
Figure 1: Shared FlinkSQL gateway architecture

We split our solution into 3 layers:

  • Compute layer
  • Integration layer
  • Query layer

Users first interact with our platform portal to submit queries for data from Kafka online store using SQL (1). Upon submission, our backend orchestrator then creates a session for the user (2) and submits the SQL query to our FlinkSQL gateway using their inbuilt REST API (3). The FlinkSQL gateway then packages the SQL query into a Flink job to be submitted to our Flink session cluster (4) before collating its results. The subsequent results would be polled from the query layer to be displayed back to the user.

Compute layer

With FlinkSQL gateway acting as the main compute engine for ad-hoc queries, it is now more straightforward to perform Flink version upgrades along with our solution, since the FlinkSQL gateway is packaged along with the main Flink distribution. We do not need to maintain Flink shims for each version as adapters between the Flink compute cluster and Zeppelin notebook cluster.

Another advantage of using the shared FlinkSQL gateway was the reduced cold start time for each ad-hoc queries. Since all users share the same FlinkSQL cluster instead of having their own Zeppelin cluster, there was no need to wait for cluster startup during initialisation of their sessions. This brought the lead time to the first results displayed down from 5 minutes to 1 minute. There was still lead time involved as the tool provisions task managers on an ad-hoc basis to balance availability of such developer tools and the associated cost.

Integration layer

The Integration layer serves as the glue between the user-facing query layer and the underlying compute layer, ensuring seamless communication and security across our ecosystem. With the shift to a shared FlinkSQL gateway, we recognised the need for an intermediary that could handle authentication, authorisation, orchestration, and integration with internal platforms – all while abstracting the complexities of Flink’s native REST API.

Figure 2: FlinkSQL gateway

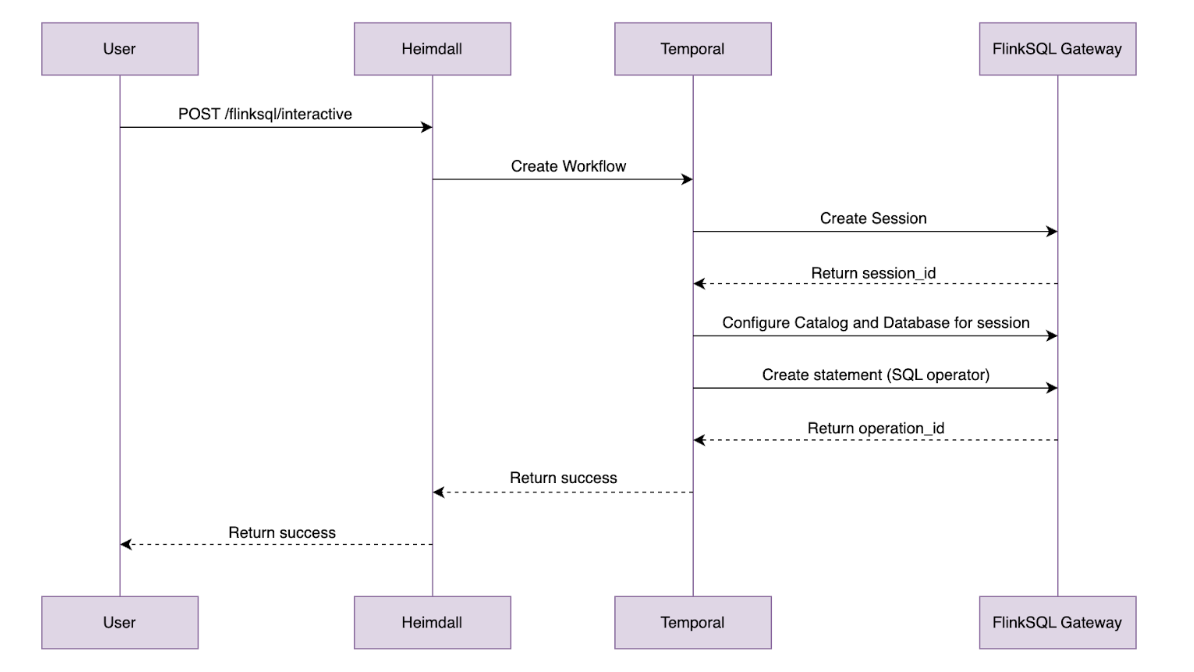
The FlinkSQL gateway’s built-in REST API gets the job done for basic query submission, but it falls short in areas like session management, requiring multiple POST requests just to fetch results. To address this, we extended a custom control plane with its own set of REST APIs, layered on top of the gateway.

We then extend these sessions and integrate them to our inhouse authentication and authorisation platform. For each query made, the control plane authenticates the user, spins up lightweight sessions and manages the communication between the caller and the Flink Session Cluster. If you are interested, check out our previous blog post, An elegant platform, for more details on the above mentioned streaming platform and its control plane.

curl --location 'https://example.com/v1/flink/flinksql/interactive' \
--header 'Content-Type: application/json' \
--header 'Authorization: Bearer ...' \
--data '{
    "environment" : "prd",
    "namespace" : "flink",
    "sql" : "SELECT * FROM titanicstream"}'

Example API request for running a FlinkSQL query

The integration layer also caters to B2B needs via our Headless APIs. By exposing the endpoints, developers are able to integrate real-time processing into their own tools. To run a query, programs can simply make a POST request with the SQL query and an operation ID would be returned. This operation ID could then be used in subsequent GET requests to fetch the paginated results of the unbounded query. This setup is ideal for internal platforms that need to query Kafka data programmatically. By abstracting these complexities, it ensures that users, whether individual analysts or internal platforms—can tap into Kafka data without wrestling with Flink’s raw interfaces.

Query layer

We then proceed to pair our APIs developed with an Interactive UI to build a Query layer that serves both human workflows. This is where users meet our platform.

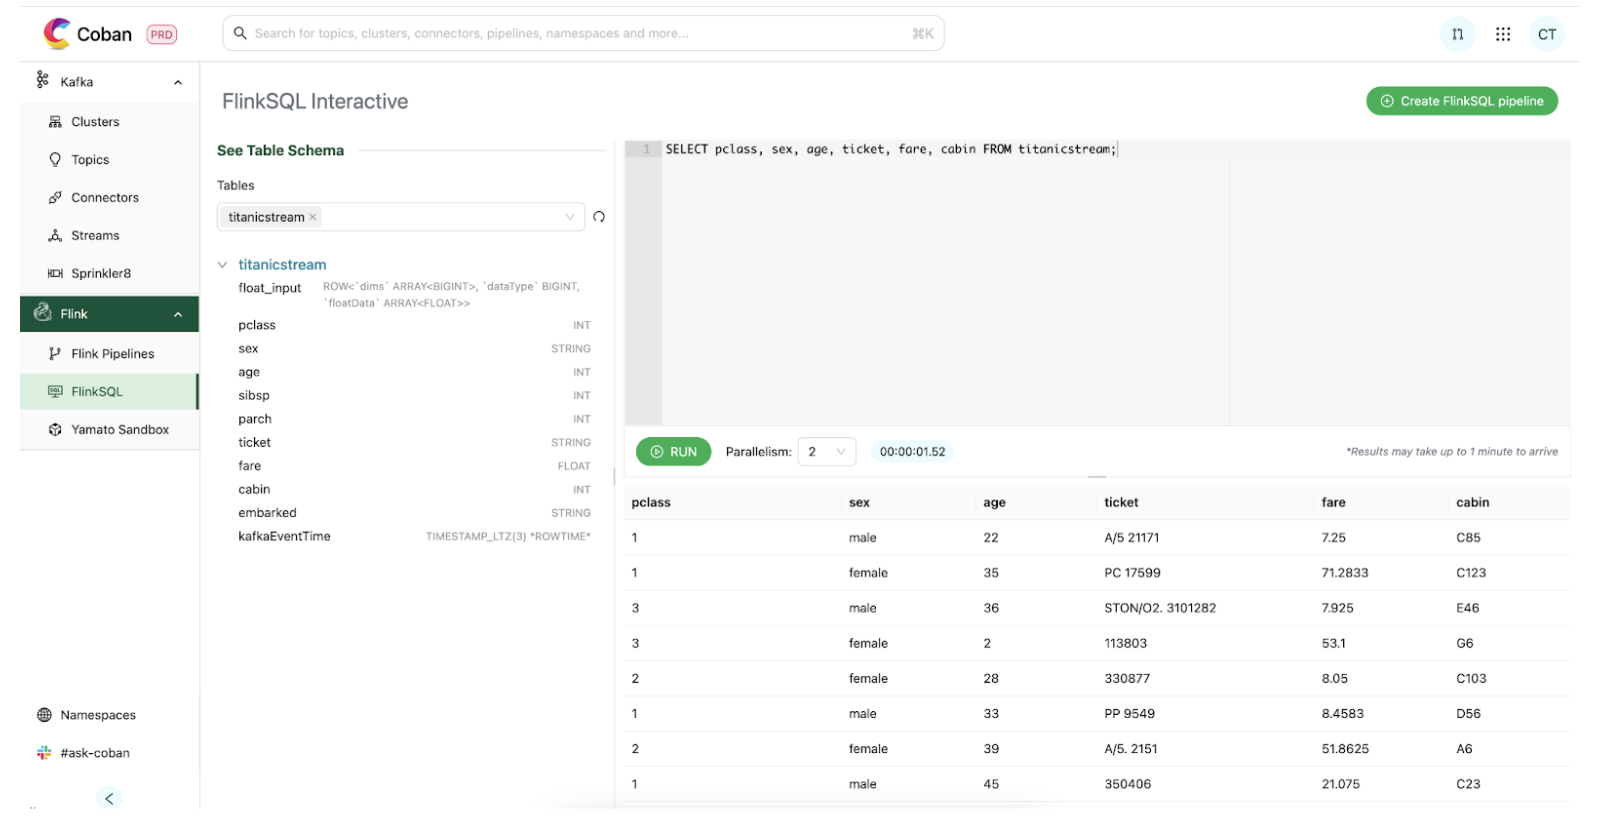
Figure 3: Flink query layer’s user flow

Through our platform portal, users land in a clean SQL editor. We used a Hive Metastore (HMS) catalog that translates Kafka topics into tables. Users don’t need to decode stream internals; they can jump straight into it by simply selecting a table to query on. Once a query is submitted, it is then handled by the integration layer which routes it through the control plane to the gateway. Results are then streamed back, appearing in the UI within one minute, a significant improvement from the five minute Zeppelin cold starts.

This all crystalises into the user flow demonstrated in Figure 3, where we can easily retrieve Titanic data from a Kafka stream with a short command:

SELECT COUNT(*) FROM titanicstream WHERE kafkaEventTime > NOW() - INTERVAL '1' HOUR.

This setup enables a few use cases for our teams, such as:

  • Fraud analysts using the real-time data to debug and spot patterns in fraudulent transactions.
  • Data scientists querying live signals to validate their prediction models.
  • Engineers validating the messages sent from their system to confirm they are properly structured and accurately delivered.

Productionising FlinkSQL

With data being democratised, we see more users building use cases around our online data store and utilising the above tools to build new stream processing pipelines expressed as SQL queries. To simplify the last step of the software development lifecycle of deployment, we have also developed a tool to create a configuration based stream processing pipeline, with the business logic expressed as a SQL statement.

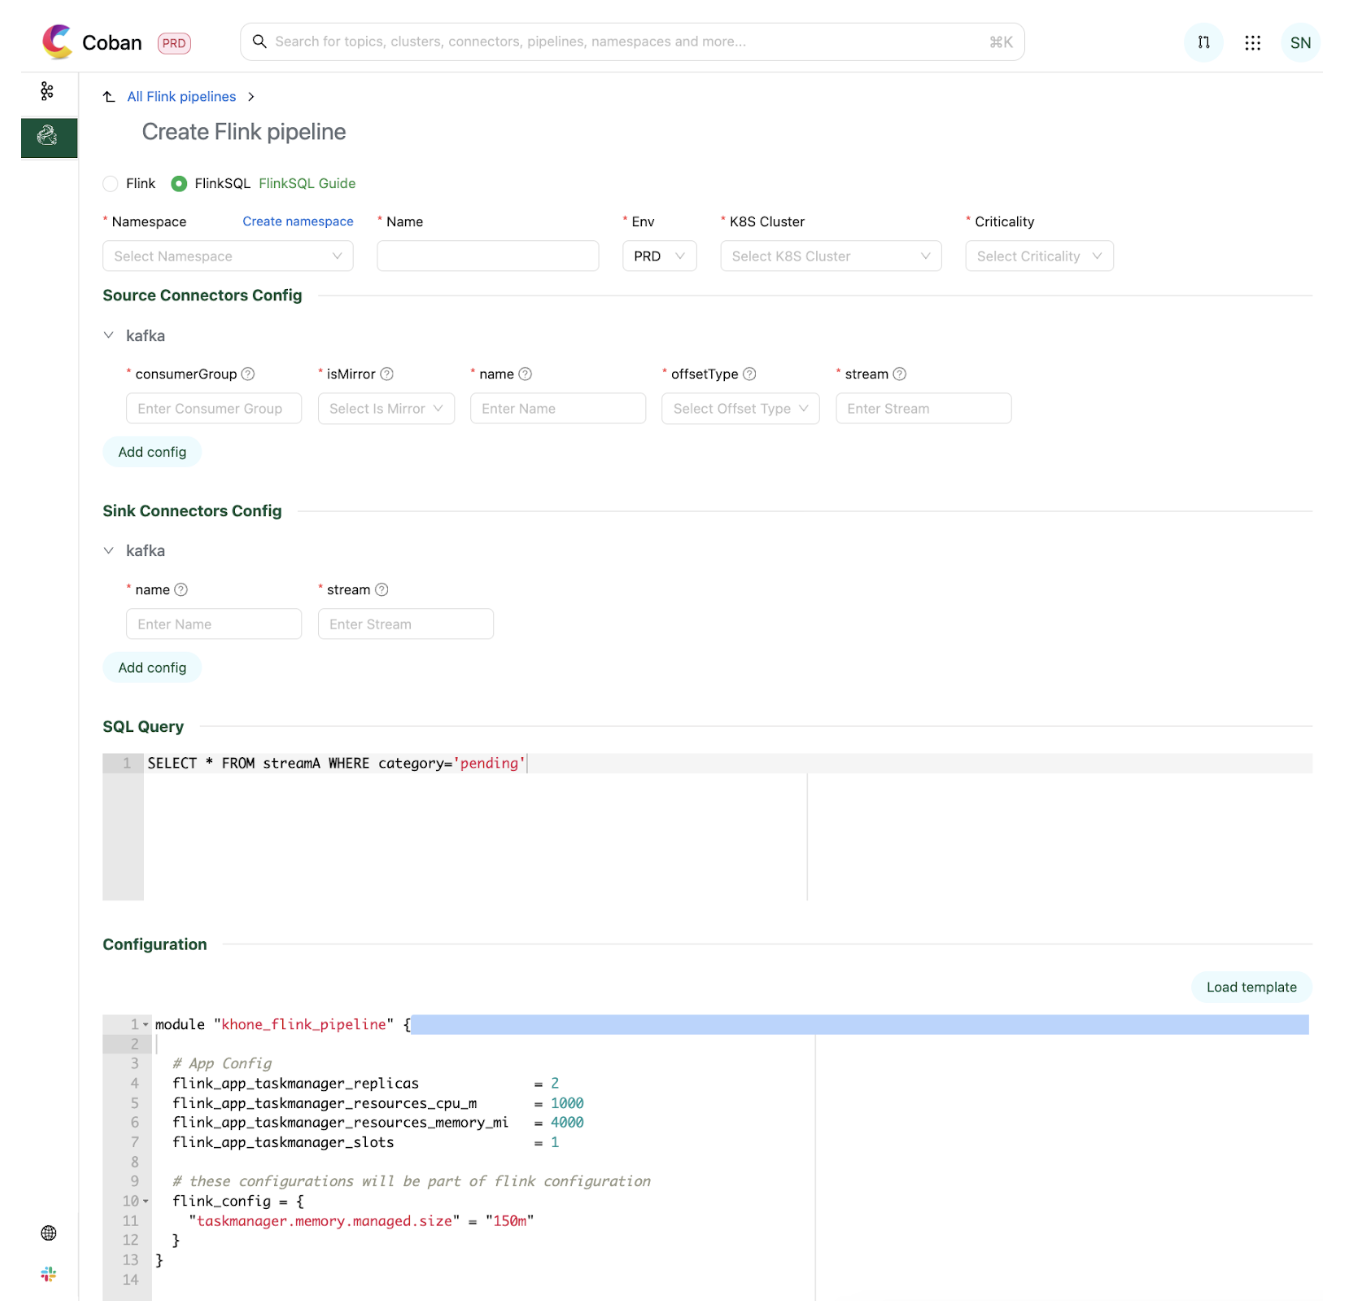
Figure 4: Portal for FlinkSQL pipeline creation

We host connectors for users to connect to other platforms within Grab, such as Kafka and our internal feature stores. Users could simply use them off-the-shelf and configure according to their needs before deploying their stream processing pipeline.

Users would then proceed to submit their streaming logic as a SQL statement. In the example illustrated in the diagram, the logic expressed is a simple filter on a Kafka stream for sinking the filtered events into a separate Kafka stream.

Users have the ability to then define the parallelism and associated resources they want to run their Flink jobs with. Upon submission, the associated resources would be provisioned and the Flink pipeline would be automatically deployed. Behind the scenes, we manage the application JAR file that is being used to run the job that dynamically parses these configurations and translates them into a proper Flink job graph to be submitted to the Flink cluster.

Within 10 minutes, users would have completed deploying their stream processing pipeline to production.

Conclusion

With our full suite of solutions for low code development via FlinkSQL, from exploration and design, to development and then deployment, we have simplified the journey for developing business use cases off online streaming stores. By offering both a user-friendly interface for low-code users and a robust API for developers, these tools empower businesses to harness the full potential of real-time data processing. Whether you are a data analyst looking for quick insights or a developer integrating real-time analytics into your applications, our tools are able to lower the barrier of entry to utilising real-time data.

After we released these solutions, we quickly saw an uptick in pipelines created as well as the number of interactive queries fired. This result was encouraging and we hope that this would gradually bring upon a paradigm shift, enabling Grab to make data-driven operational decisions on real-time signals, empowering us with the ability to react to ever-changing market conditions in the most efficient manner.

Join us

Grab is a leading superapp in Southeast Asia, operating across the deliveries, mobility and digital financial services sectors. Serving over 800 cities in eight Southeast Asian countries, Grab enables millions of people everyday to order food or groceries, send packages, hail a ride or taxi, pay for online purchases or access services such as lending and insurance, all through a single app. Grab was founded in 2012 with the mission to drive Southeast Asia forward by creating economic empowerment for everyone. Grab strives to serve a triple bottom line – we aim to simultaneously deliver financial performance for our shareholders and have a positive social impact, which includes economic empowerment for millions of people in the region, while mitigating our environmental footprint.

Powered by technology and driven by heart, our mission is to drive Southeast Asia forward by creating economic empowerment for everyone. If this mission speaks to you, join our team today!

Monitoring AWS End User Messaging SMS Registrations with Lambda

Post Syndicated from Patrick Viker original https://aws.amazon.com/blogs/messaging-and-targeting/monitoring-aws-end-user-messaging-sms-registrations-with-lambda/

Managing AWS End User Messaging SMS registrations can be challenging, especially when dealing with multiple registrations in various states and countries. This post introduces an automated monitoring solution that helps you stay on top of your registration statuses. By leveraging AWS Lambda, EventBridge, and Simple Email Service (SES), you’ll create a system that provides regular updates about registrations that need attention, are under review, in draft pending submission, or have recently been completed.

Whether you’re managing Sender IDs, United States 10DLC campaigns, toll-free numbers, or short codes, this solution will help you maintain visibility across all your registrations and respond promptly to status changes. The setup takes approximately 15-20 minutes and requires no ongoing maintenance beyond occasional adjustments to meet your evolving needs.

Estimated Setup Time: 15-20 minutes

Prerequisites

  • An AWS account with access to Lambda, IAM, EventBridge, End User Messaging SMS, and SES
  • A verified email address in Amazon SES for sending reports.
Figure 1: AWS End User Messaging SMS registrations in the console. This view shows registrations in various states that our Lambda function will monitor.

Figure 1: AWS End User Messaging SMS registrations in the console. This view shows registrations in various states that our Lambda function will monitor.

Step 1: Set up Amazon SES

  1. Open the Amazon SES console
  2. Navigate to “Verified identities”
  3. If you have an identity verified you can skip this section
  4. If you do not already have an identity verified Click “Create identity”
  5. Review this post to learn how to verify an identity
    NOTE: Best practice is to verify a domain identity. This will authenticate your domain and improve deliverability. An email address identity, while more simple, will not be authenticated through DKIM which may decrease deliverability.

Reference: Creating and verifying identities in Amazon SES

Step 2: Create an IAM Role

  1. Open the IAM console
  2. Navigate to “Roles” and click “Create role”
  3. Select “AWS service” and “Lambda” as the use case
  4. Add only the following AWS managed policy: AWSLambdaBasicExecutionRole
  5. Name the role (e.g., “EndUserMessagingRegistrationsMonitorRole”) and click “Create role”
  6. After role creation, click on the newly created role
  7. Select “Add permissions” → “Create inline policy”
  8. Click on the “JSON” tab and paste the following policy:
    {
        "Version": "2012-10-17",
        "Statement": [
            {
                "Effect": "Allow",
                "Action": [
                    "sms-voice:DescribeRegistrations",
                    "sms-voice:DescribeRegistrationVersions"
                ],
                "Resource": "arn:aws:sms-voice:${region}:${account-id}:registration/*"
            },
            {
                "Effect": "Allow",
                "Action": "ses:SendRawEmail",
                "Resource": [
                    "arn:aws:ses:${region}:${account-id}:identity/${domain}",
                    "arn:aws:ses:${region}:${account-id}:configuration-set/*"
                ],
                "Condition": {
                    "StringLike": {
                        "ses:FromAddress": [
                            "*@${domain}"
                        ]
                    }
                }
            }
        ]
    }
  9. Replace the placeholders in the policy:
    1. ${region}: Your AWS region (e.g., ‘us-west-2’)
    2. ${account-id}: Your AWS account ID
    3. ${domain}: Your verified SES domain
  10. Click “Next”
  11. Name the policy (e.g., “EndUserMessagingRegistrationsAccess”) and click “Create policy”

Reference: Creating a role for an AWS service (console)

Step 3: Create the Lambda Function

  1. Open the Lambda console
  2. Click “Create function”
  3. Choose “Author from scratch”
  4. Configure basic settings:
  5. Name: EndUserMessagingRegistrationsMonitor
  6. Runtime: Python 3.12
  7. Architecture: x86_64
  8. Permissions: Use the IAM role created in Step 2
  9. Click “Create function”
  10. Configure environment variables:
    1. Under “Configuration” tab → “Environment variables”
    2. Set the following key/value pairs:
      1. Key: SENDER_EMAIL, Value: [Your verified SES email]
      2. Key: RECIPIENT_EMAIL, Value: [Email to receive reports]
  11. Configure function timeout:
    1. Under “Configuration” → “General configuration”
    2. Set timeout to 1 minute
  12. In the function code area, paste the following code:
    import boto3
    import json
    from datetime import datetime, timedelta
    from collections import defaultdict
    from email.mime.text import MIMEText
    from email.mime.multipart import MIMEMultipart
    import os
    
    # Constants
    REGION = os.environ['AWS_REGION']
    SENDER_EMAIL = os.environ['SENDER_EMAIL']
    RECIPIENT_EMAIL = os.environ['RECIPIENT_EMAIL']
    COMPLETED_LOOKBACK_DAYS = 7
    
    # Initialize AWS clients
    sms_client = boto3.client('pinpoint-sms-voice-v2', region_name=REGION)
    ses_client = boto3.client('ses', region_name=REGION)
    
    # Global registration dictionary
    registrations = {
        'REQUIRES_UPDATES': defaultdict(list),
        'CREATED': defaultdict(list),
        'COMPLETED': defaultdict(list),
        'REVIEWING': defaultdict(list)
    }
    
    def get_console_url(registration_id):
        return f"https://{REGION}.console.aws.amazon.com/sms-voice/home?region={REGION}#/registrations?registration-id={registration_id}"
    
    def get_version_details(registration_id, latest_denied_version=None):
        try:
            if latest_denied_version:
                response = sms_client.describe_registration_versions(
                    RegistrationId=registration_id,
                    VersionNumbers=[latest_denied_version]
                )
            else:
                response = sms_client.describe_registration_versions(
                    RegistrationId=registration_id,
                    MaxResults=1
                )
            
            if response['RegistrationVersions']:
                return response['RegistrationVersions'][0]
        except Exception as e:
            print(f"Error getting version details for {registration_id}: {str(e)}")
        return None
    
    def is_recently_completed(version_info):
        if 'RegistrationVersionStatusHistory' in version_info:
            history = version_info['RegistrationVersionStatusHistory']
            if 'ApprovedTimestamp' in history:
                approved_time = history['ApprovedTimestamp']
                if isinstance(approved_time, datetime):
                    approved_time = approved_time.timestamp()
                lookback_time = (datetime.now() - timedelta(days=COMPLETED_LOOKBACK_DAYS)).timestamp()
                return approved_time > lookback_time
        return False
    
    def categorize_registration_type(registration_type):
        if 'TEN_DLC' in registration_type:
            return 'TEN_DLC'
        elif 'LONG_CODE' in registration_type:
            return 'LONG_CODE'
        elif 'SHORT_CODE' in registration_type:
            return 'SHORT_CODE'
        elif 'SENDER_ID' in registration_type:
            return 'SENDER_ID'
        elif 'TOLL_FREE' in registration_type:
            return 'TOLL_FREE'
        else:
            return 'OTHER'
    
    def categorize_registrations():
        global registrations
        registrations = {
            'REQUIRES_UPDATES': defaultdict(list),
            'CREATED': defaultdict(list),
            'COMPLETED': defaultdict(list),
            'REVIEWING': defaultdict(list)
        }
    
        try:
            response = sms_client.describe_registrations()
            
            for registration in response.get('Registrations', []):
                status = registration['RegistrationStatus']
                registration_id = registration['RegistrationId']
                registration_type = registration['RegistrationType']
                category = categorize_registration_type(registration_type)
                
                reg_info = {
                    'id': registration_id,
                    'type': registration_type,
                    'status': status,
                    'version': registration['CurrentVersionNumber'],
                    'console_url': get_console_url(registration_id)
                }
    
                if 'AdditionalAttributes' in registration:
                    reg_info['additional_attributes'] = registration['AdditionalAttributes']
    
                if status == 'REQUIRES_UPDATES':
                    latest_denied_version = registration.get('LatestDeniedVersionNumber')
                    version_info = get_version_details(registration_id, latest_denied_version)
                    if version_info and 'DeniedReasons' in version_info:
                        reg_info['denial_reasons'] = version_info['DeniedReasons']
                    registrations['REQUIRES_UPDATES'][category].append(reg_info)
                
                elif status == 'CREATED':
                    registrations['CREATED'][category].append(reg_info)
                
                elif status == 'REVIEWING':
                    registrations['REVIEWING'][category].append(reg_info)
                
                elif status == 'COMPLETE':
                    version_info = get_version_details(registration_id)
                    if version_info and is_recently_completed(version_info):
                        approved_timestamp = version_info['RegistrationVersionStatusHistory']['ApprovedTimestamp']
                        if isinstance(approved_timestamp, datetime):
                            approved_timestamp = approved_timestamp.timestamp()
                        reg_info['approved_timestamp'] = approved_timestamp
                        registrations['COMPLETED'][category].append(reg_info)
                    
        except Exception as e:
            print(f"Error listing registrations: {str(e)}")
            raise e
    
    def generate_html_output():
        html = """
        <html>
        <head>
            <style>
                body { 
                    font-family: Arial, sans-serif;
                    margin: 20px;
                    line-height: 1.6;
                }
                .registration-group { margin: 20px 0; }
                .registration-category { 
                    background-color: #f0f0f0;
                    padding: 10px;
                    margin: 10px 0;
                    border-radius: 5px;
                }
                .registration-item {
                    border-left: 4px solid #ccc;
                    margin: 10px 0;
                    padding: 10px;
                    background-color: #ffffff;
                }
                .requires-updates { border-left-color: #ff9900; }
                .created { border-left-color: #007bff; }
                .completed { border-left-color: #28a745; }
                .reviewing { border-left-color: #6c757d; }
                .denial-reasons {
                    background-color: #fff3f3;
                    padding: 10px;
                    margin: 5px 0;
                    border-radius: 3px;
                }
                .console-link {
                    color: #007bff;
                    text-decoration: none;
                    padding: 2px 5px;
                    border: 1px solid #007bff;
                    border-radius: 3px;
                }
                .console-link:hover {
                    background-color: #007bff;
                    color: #ffffff;
                }
                .summary {
                    margin: 20px 0;
                    padding: 15px;
                    background-color: #e9ecef;
                    border-radius: 5px;
                    box-shadow: 0 2px 4px rgba(0,0,0,0.1);
                }
                .divider {
                    border-top: 2px solid #dee2e6;
                    margin: 20px 0;
                }
                .lookback-info {
                    background-color: #e2e3e5;
                    padding: 10px;
                    border-radius: 5px;
                    margin: 10px 0;
                    font-style: italic;
                }
                h2, h3, h4 {
                    color: #333;
                    margin-top: 20px;
                }
                ul {
                    margin: 5px 0;
                    padding-left: 20px;
                }
                li {
                    margin: 5px 0;
                }
            </style>
        </head>
        <body>
        """
    
        html += f"<h2>Registration Status Report - {datetime.now().strftime('%Y-%m-%d %H:%M:%S')}</h2>"
    
        html += f"""
        <div class="lookback-info">
            Note: Completed registrations shown are those completed within the last {COMPLETED_LOOKBACK_DAYS} days.
        </div>
        """
    
        html += '<div class="summary"><h3>Summary</h3>'
        for status, categories in registrations.items():
            total = sum(len(regs) for regs in categories.values())
            html += f"<p><strong>{status}:</strong> {total}"
            if status == 'COMPLETED':
                html += f" (last {COMPLETED_LOOKBACK_DAYS} days)"
            html += "<br>"
            for category, regs in categories.items():
                if regs:
                    html += f"&nbsp;&nbsp;{category}: {len(regs)}<br>"
            html += "</p>"
        grand_total = sum(sum(len(regs) for regs in categories.values()) for categories in registrations.values())
        html += f"<p><strong>Total Registrations:</strong> {grand_total}</p>"
        html += "</div>"
    
        html += '<div class="divider"></div>'
    
        html += "<h3>Detailed Registration Status</h3>"
    
        for status, categories in registrations.items():
            total = sum(len(regs) for regs in categories.values())
            html += f"""
            <div class="registration-group">
                <h3>{status} Registrations (Total: {total})</h3>
            """
    
            for category, regs in categories.items():
                if regs:
                    html += f"""
                    <div class="registration-category">
                        <h4>{category} Registrations ({len(regs)})</h4>
                    """
    
                    for reg in regs:
                        css_class = status.lower().replace('_', '-')
                        html += f"""
                        <div class="registration-item {css_class}">
                            <strong>Registration ID:</strong> {reg['id']}<br>
                            <strong>Type:</strong> {reg['type']}<br>
                            <strong>Status:</strong> {reg['status']}<br>
                            <strong>Version:</strong> {reg['version']}<br>
                            <strong>Console:</strong> <a href="{reg['console_url']}" class="console-link" target="_blank">Open in Console</a><br>
                        """
    
                        if (reg['type'] == 'US_TEN_DLC_BRAND_VETTING' and 
                            status == 'COMPLETED' and 
                            'additional_attributes' in reg and 
                            'VETTING_SCORE' in reg['additional_attributes']):
                            html += f"<strong>Vetting Score:</strong> {reg['additional_attributes']['VETTING_SCORE']}<br>"
    
                        if status == 'REQUIRES_UPDATES' and reg.get('denial_reasons'):
                            html += '<div class="denial-reasons"><strong>Denial Reasons:</strong><ul>'
                            for reason in reg['denial_reasons']:
                                html += f"""
                                <li>
                                    <strong>{reason.get('Reason', 'N/A')}</strong><br>
                                    {reason.get('ShortDescription', 'N/A')}<br>
                                """
                                if reason.get('LongDescription'):
                                    html += f"{reason['LongDescription']}<br>"
                                if reason.get('DocumentationLink'):
                                    html += f'<a href="{reason["DocumentationLink"]}" target="_blank">Documentation</a>'
                                html += "</li>"
                            html += "</ul></div>"
    
                        if status == 'COMPLETED':
                            approved_time = datetime.fromtimestamp(reg['approved_timestamp']).strftime('%Y-%m-%d %H:%M:%S')
                            html += f"<strong>Approved:</strong> {approved_time}<br>"
    
                        html += "</div>"
                    html += "</div>"
            html += "</div>"
    
        html += "</body></html>"
        return html
    
    def send_email(html_content, subject, recipient):
        msg = MIMEMultipart('mixed')
        msg['Subject'] = subject
        msg['From'] = SENDER_EMAIL
        msg['To'] = recipient
    
        html_part = MIMEText(html_content, 'html')
        msg.attach(html_part)
    
        try:
            response = ses_client.send_raw_email(
                Source=msg['From'],
                Destinations=[recipient],
                RawMessage={'Data': msg.as_string()}
            )
            print(f"Email sent! Message ID: {response['MessageId']}")
        except Exception as e:
            print(f"Error sending email: {str(e)}")
            raise e
    
    def lambda_handler(event, context):
        try:
            print("Starting registration categorization...")
            categorize_registrations()
            
            print("Generating HTML report...")
            html_content = generate_html_output()
            
            print("Sending email...")
            subject = f"End User Messaging SMS Registration Status Report - {datetime.now().strftime('%Y-%m-%d %H:%M')}"
            send_email(html_content, subject, RECIPIENT_EMAIL)
            
            return {'statusCode': 200, 'body': json.dumps('Registration status report generated and sent successfully')}
        except Exception as e:
            print(f"Error in lambda execution: {str(e)}")
            return {'statusCode': 500, 'body': json.dumps(f'Error generating report: {str(e)}')}

Reference: Building Lambda functions with Python

Step 4: Set Up EventBridge Rule

  1. Open the Amazon EventBridge console
  2. Click “Create rule”
  3. Name your rule (e.g., “EndUserMessagingRegistrationsMonitorSchedule”)
  4. For the event pattern, choose “Schedule” then select “Continue in EventBridge Scheduler”
  5. Configure your schedule pattern to your requirements (for example, Cron-based schedule to run at specific days and times or rate-based schedule such as every 1 day). Click “Next”.
  6. Select “Lambda” for “Target detail” and select the Lambda function created in Step 3 as the target from the dropdown. Click “Next”.
  7. For permissions:
    1. Select “Create new role for this schedule”
    2. EventBridge will automatically create a role with the necessary permissions to invoke your Lambda function
  8. Click “Next” to review your configuration
  9. Click “Create schedule”

Reference: Amazon EventBridge Scheduler

Step 5: Test the Setup

  1. Open the Lambda console and navigate to your function
  2. Click “Test” and create a test event (you can use an empty JSON object {})
  3. Run the test and check the execution results
  4. Verify that you receive an email report

Reference: Testing Lambda functions in the console

The generated email report provides a clear summary of all registrations, categorized by their status.

Figure 2: The generated email report provides a clear summary of all registrations, categorized by their status.

Understanding the Lambda Function

Let’s break down the key components of our Lambda function:

  1. Initialization: The script sets up necessary AWS clients and defines constants.
  2. categorize_registrations(): This function fetches all registrations and categorizes them based on their status and type.
  3. generate_html_output(): Creates a formatted HTML report of the registration statuses.
  4. send_email(): Uses Amazon SES to send the HTML report via email.
  5. lambda_handler(): The main entry point for the Lambda function, orchestrating the entire process.

The function categorizes registrations into four main statuses:

  • REQUIRES_UPDATES: Registrations that need attention or modifications
  • CREATED: Newly created registrations
  • REVIEWING: Registrations currently under review
  • COMPLETED: Registrations that have been approved recently (within the last 7 days by default)
Detailed view of a registration requiring updates and created registrations pending submission, including specific denial reasons if applicable and direct console links.

Figure 3: Detailed view of a registration requiring updates and created registrations pending submission, including specific denial reasons if applicable and direct console links.

Customization Options

  1. Lookback Period: Modify the COMPLETED_LOOKBACK_DAYS constant to change how far back the function checks for completed registrations.
  2. Email Formatting: Adjust the HTML and CSS in generate_html_output() to customize the email report’s appearance.
  3. Additional Data: Modify the reg_info dictionary in categorize_registrations() to include more data fields in your report.

Monitoring and Maintenance

  1. CloudWatch Logs: Regularly check the Lambda function’s CloudWatch Logs for any errors or unexpected behavior.
  2. Adjusting Schedule: If you find the current schedule doesn’t meet your needs, adjust the EventBridge rule accordingly.

Conclusion

You now have an automated system that monitors your End User Messaging SMS registrations and sends you regular, detailed status reports. This setup provides:

  • Automated visibility into registrations requiring updates or attention
  • Clear tracking of draft registrations awaiting your submission
  • Monitoring of registrations under review
  • Notifications of recently completed registrations
  • A consolidated view of all registration states through formatted email reports

This automated solution eliminates the need for manual status checking and helps ensure timely responses to registration changes. As your messaging needs grow, you can easily customize the monitoring frequency, lookback period, and report format to match your requirements.

Next Steps:

  • Consider adjusting the EventBridge schedule based on your registration volume
  • Customize the email format to highlight information most relevant to your team
  • Set up CloudWatch alarms to monitor the Lambda function’s health
  • Review and update the completed registrations lookback period as needed

For more complex scenarios, consider extending this solution with additional features like Slack notifications, registration metrics tracking, or integration with your ticketing system.


AWS completes Police-Assured Secure Facilities (PASF) audit in Europe (London) AWS Region

Post Syndicated from Vishal Pabari original https://aws.amazon.com/blogs/security/aws-completes-police-assured-secure-facilities-pasf-audit-in-europe-london-aws-region/

We’re excited to announce that our Europe (London) AWS Region has renewed its accreditation for United Kingdom (UK) Police-Assured Secure Facilities (PASF) for Official-Sensitive data. Since 2017, the Amazon Web Services (AWS) Europe (London) Region has been accredited under the PASF program. This demonstrates our continuous commitment to adhere to the heightened expectations of customers with UK law enforcement workloads. Our UK law enforcement customers who require PASF can continue to run their applications in the PASF-accredited Europe (London) Region in confidence.

The PASF is a long-established assurance process, used by UK law enforcement, as a method for assuring the security of facilities such as data centers or other locations that house critical business applications that process or hold police data. PASF consists of a control set of security requirements, an on-site inspection, and an audit interview with representatives of the facility.

The Police Digital Service (PDS) confirmed the accreditation renewal for AWS on May 27, 2025. A confirmation letter can be found on AWS Artifact. The UK police force and law enforcement organizations can also obtain confirmation of the compliance status of AWS through the Police Digital Service.

To learn more about our compliance and security programs, see AWS Compliance Programs. As always, we value your feedback and questions; reach out to the AWS Compliance team through the Contact Us page.

Reach out to your AWS account team if you have questions or feedback about PASF compliance.

If you have feedback about this post, submit comments in the Comments section below.

Vishal Pabari

Vishal Pabari

Vishal is a Security Assurance Program Manager at AWS, based in London, UK. Vishal is responsible for third-party and customer audits, attestations, certifications, and assessments across EMEA. Vishal previously worked in risk and control, and technology in the financial services industry.

Tea Jioshvili

Tea Jioshvili

Tea is a Manager in AWS Security Assurance based in Berlin, Germany. She leads various third-party audit programs across Europe. She previously worked in security assurance and compliance, business continuity, and operational risk management in the financial industry for multiple years.

[$] Finding locking bugs with Smatch

Post Syndicated from daroc original https://lwn.net/Articles/1023646/

Smatch is a GPL-licensed
static-analysis tool for C that has a lot of specialized checks for the kernel. Smatch
has been used in the kernel for more than 20 years; Dan
Carpenter, its primary author, decided last year that some details of its plugin system
were due for a rewrite. He spoke at Linaro Connect 2025 about his work on
Smatch, the changes to its implementation, and how those changes enabled him to easily
add additional checks for locking bugs in the kernel.

Covert web-to-app tracking via localhost on Android

Post Syndicated from corbet original https://lwn.net/Articles/1024844/

The “Local Mess” GitHub
repository
is dedicated to the disclosure of an Android tracking
exploit used by (at least) Meta and Yandex.

While there are subtle differences in the way Meta and Yandex
bridge web and mobile contexts and identifiers, both of them
essentially misuse the unvetted access to localhost sockets. The
Android OS allows any installed app with the INTERNET permission to
open a listening socket on the loopback interface
(127.0.0.1). Browsers running on the same device also access this
interface without user consent or platform mediation. This allows
JavaScript embedded on web pages to communicate with native Android
apps and share identifiers and browsing habits, bridging ephemeral
web identifiers to long-lived mobile app IDs using standard Web
APIs.

This backdoor, the use of which has evidently stopped since its disclosure,
allow tracking of users across sites regardless of cookie policies or use of
incognito browser modes.

Security updates for Wednesday

Post Syndicated from jzb original https://lwn.net/Articles/1024939/

Security updates have been issued by AlmaLinux (glibc, grafana, kernel-rt, libjpeg-turbo, libxslt, and thunderbird), Debian (curl), Fedora (dtk6core, dtk6gui, dtk6log, dtk6widget, fcitx5-qt, gammaray, kddockwidgets, kwin, LabPlot, libqtxdg, nheko, plasma-integration, python-pyqt6, python-pyside6, qt-creator, roundcubemail, zeal, and a large number of qt6 packages), Oracle (firefox, glibc, grafana, kernel, libxslt, perl-FCGI, python3.12-cryptography, thunderbird, and zlib), SUSE (glib2, libjxl, libsoup2, nbdkit, nodejs22, perl-Crypt-OpenSSL-RSA, perl-YAML-LibYAML, python3, tomcat, and transfig), and Ubuntu (dotnet8, dotnet9 and samba).

We shipped FinalizationRegistry in Workers: why you should never use it

Post Syndicated from Ketan Gupta original https://blog.cloudflare.com/we-shipped-finalizationregistry-in-workers-why-you-should-never-use-it/

We’ve recently added support for the FinalizationRegistry API in Cloudflare Workers. This API allows developers to request a callback when a JavaScript object is garbage-collected, a feature that can be particularly relevant for managing external resources, such as memory allocated by WebAssembly (Wasm). However, despite its availability, our general advice is: avoid using it directly in most scenarios.

Our decision to add FinalizationRegistry — while still cautioning against using it — opens up a bigger conversation: how memory management works when JavaScript and WebAssembly share the same runtime. This is becoming more common in high-performance web apps, and getting it wrong can lead to memory leaks, out-of-memory errors, and performance issues, especially in resource-constrained environments like Cloudflare Workers.

In this post, we’ll look at how JavaScript and Wasm handle memory differently, why that difference matters, and what FinalizationRegistry is actually useful for. We’ll also explain its limitations, particularly around timing and predictability, walk through why we decided to support it, and how we’ve made it safer to use. Finally, we’ll talk about how newer JavaScript language features offer a more reliable and structured approach to solving these problems.

Memory management 101

JavaScript

JavaScript relies on automatic memory management through a process called garbage collection. This means developers do not need to worry about freeing allocated memory, or lifetimes. The garbage collector identifies and reclaims memory occupied by objects that are no longer needed by the program (that is, garbage). This helps prevent memory leaks and simplifies memory management for developers.

function greet() {
  let name = "Alice";         // String is allocated in memory
  console.log("Hello, " + name);
}                             // 'name' goes out of scope

greet();
// JavaScript automatically frees allocated memory at some point in future

WebAssembly

WebAssembly (Wasm) is an assembly-like instruction format designed to run high-performance applications on the web. While it initially gained prominence in web browsers, Wasm is also highly effective on the server side. At Cloudflare, we leverage Wasm to enable users to run code written in a variety of programming languages, such as Rust and Python, directly within our V8 isolates, offering both performance and versatility.

Wasm runtimes are designed to be simple stack machines, and lack built-in garbage collectors. This necessitates manual memory management (allocation and deallocation of memory used by Wasm code), making it an ideal compilation target for languages like Rust and C++ that handle their own memory.

Wasm modules operate on linear memory: a resizable block of raw bytes, which JavaScript views as an ArrayBuffer. This memory is organized in 64 KB pages, and its initial size is defined when the module is compiled or loaded. Wasm code interacts with this memory using 32-bit offsets — integer values functioning as direct pointers that specify a byte offset from the start of its linear memory. This direct memory access model is crucial for Wasm’s high performance. The host environment (which in Cloudflare Workers is JavaScript) also shares this ArrayBuffer, reading and writing (often via TypedArrays) to enable vital data exchange between Wasm and JavaScript.


A core Wasm design is its secure sandbox. This confines Wasm code strictly to its own linear memory and explicitly declared imports from the host, preventing unauthorized memory access or system calls. Direct interaction with JavaScript objects is blocked; communication occurs through numeric values, function references, or operations on the shared ArrayBuffer. This strong isolation is vital for security, ensuring Wasm modules don’t interfere with the host or other application components, which is especially important in multi-tenant environments like Cloudflare Workers.


Bridging WebAssembly memory with JavaScript often involves writing low-level “glue” code to convert raw byte arrays from Wasm into usable JavaScript types. Doing this manually for every function or data structure is both tedious and error-prone. Fortunately, tools like wasm-bindgen and Emscripten (Embind) handle this interop automatically, generating the binding code needed to pass data cleanly between the two environments. We use these same tools under the hood — wasm-bindgen for Rust-based workers-rs projects, and Emscripten for Python Workers — to simplify integration and let developers focus on application logic rather than memory translation.

Interoperability

High-performance web apps often use JavaScript for interactive UIs and data fetching, while WebAssembly handles demanding operations like media processing and complex calculations for significant performance gains, allowing developers to maximize efficiency. Given the difference in memory management models, developers need  to be careful when using WebAssembly memory in JavaScript.

For this example, we’ll use Rust to compile a WebAssembly module manually. Rust is a popular choice for WebAssembly because it offers precise control over memory and easy Wasm compilation using standard toolchains.

Rust

Here we have two simple functions. make_buffer creates a string and returns a raw pointer back to JavaScript. The function intentionally “forgets” the memory allocated so that it doesn’t get cleaned up after the function returns. free_buffer, on the other hand, expects the initial string reference handed back and frees the memory.

// Allocate a fresh byte buffer and hand the raw pointer + length to JS.
// *We intentionally “forget” the Vec so Rust will not free it right away;
//   JS now owns it and must call `free_buffer` later.*
#[no_mangle]
pub extern "C" fn make_buffer(out_len: *mut usize) -> *mut u8 {
    let mut data = b"Hello from Rust".to_vec();
    let ptr = data.as_mut_ptr();
    let len  = data.len();

    unsafe { *out_len = len };

    std::mem::forget(data);
    return ptr;
}

/// Counterpart that **must** be called by JS to avoid a leak.
#[no_mangle]
pub unsafe extern "C" fn free_buffer(ptr: *mut u8, len: usize) {
    let _ = Vec::from_raw_parts(ptr, len, len);
}

JavaScript

Back in JavaScript land, we’ll call these Wasm functions and output them using console.log. This is a common pattern in Wasm-based applications since WebAssembly doesn’t have direct access to Web APIs, and rely on a JavaScript “glue” to interface with the outer world in order to do anything useful.

const { instance } = await WebAssembly.instantiate(WasmBytes, {});

const { memory, make_buffer, free_buffer } = instance.exports;

//  Use the Rust functions
const lenPtr = 0;                 // scratch word in Wasm memory
const ptr = make_buffer(lenPtr);

const len = new DataView(memory.buffer).getUint32(lenPtr, true);
const data = new Uint8Array(memory.buffer, ptr, len);

console.log(new TextDecoder().decode(data)); // “Hello from Rust”

free_buffer(ptr, len); // free_buffer must be called to prevent memory leaks

You can find all code samples along with setup instructions here.

As you can see, working with Wasm memory from JavaScript requires care, as it introduces the risk of memory leaks if allocated memory isn’t properly released. JavaScript developers are often unfamiliar with manual memory management, and it’s easy to forget returning memory to WebAssembly after use. This can become especially tricky when Wasm-allocated data is passed into JavaScript libraries, making ownership and lifetime harder to track.

While occasional leaks may not cause immediate issues, over time they can lead to increased memory usage and degrade performance, particularly in memory-constrained environments like Cloudflare Workers.

FinalizationRegistry

FinalizationRegistry, introduced as part of the TC-39 WeakRef proposal, is a JavaScript API which lets you run “finalizers” (aka cleanup callbacks) when an object gets garbage-collected. Let’s look at a simple example to demonstrate the API:

const my_registry = new FinalizationRegistry((obj) => { console.log("Cleaned up: " + obj); });

{
  let temporary = { key: "value" };
  // Register this object in our FinalizationRegistry -- the second argument,
  // "temporary", will be passed to our callback as its obj parameter
  my_registry.register(temporary, "temporary");
}

// At some point in the future when temporary object gets garbage collected, we'll see "Cleaned up: temporary" in our logs.

Let’s see how we can use this API in our Wasm-based application:

const { instance } = await WebAssembly.instantiate(WasmBytes, {});

const { memory, make_buffer, free_buffer } = instance.exports;

// FinalizationRegistry would be responsible for returning memory back to Wasm
const cleanupFr = new FinalizationRegistry(({ ptr, len }) => {
  free_buffer(ptr, len);
});

//  Use the Rust functions
const lenPtr = 0;                 // scratch word in Wasm memory
const ptr = make_buffer(lenPtr);

const len = new DataView(memory.buffer).getUint32(lenPtr, true);
const data = new Uint8Array(memory.buffer, ptr, len);

// Register the data buffer in our FinalizationRegistry so that it gets cleaned up automatically
cleanupFr.register(data, { ptr, len });

console.log(new TextDecoder().decode(data));   // → “Hello from Rust”

// No need to manually call free_buffer, FinalizationRegistry will do this for us

We can use a FinalizationRegistry to manage any object borrowed from WebAssembly by registering it with a finalizer that calls the appropriate free function. This is the same approach used by wasm-bindgen. It shifts the burden of manual cleanup away from the JavaScript developer and delegates it to the JavaScript garbage collector. However, in practice, things aren’t quite that simple.

Inherent issues with FinalizationRegistry

There is a fundamental issue with FinalizationRegistry: garbage collection is non-deterministic, and may clean up your unused memory at some arbitrary point in the future. In some cases, garbage collection might not even run and your “finalizers” will never be triggered.

This is part of its documentation as well:

“A conforming JavaScript implementation, even one that does garbage collection, is not required to call cleanup callbacks. When and whether it does so is entirely down to the implementation of the JavaScript engine. When a registered object is reclaimed, any cleanup callbacks for it may be called then, or some time later, or not at all.”

Even Emscripten mentions this in their documentation: “… finalizers are not guaranteed to be called, and even if they are, there are no guarantees about their timing or order of execution, which makes them unsuitable for general RAII-style resource management.”

Given their non-deterministic nature, developers seldom use finalizers for any essential program logic. Treat them as a last-ditch safety net, not as a primary cleanup mechanism — explicit, deterministic teardown logic is almost always safer, faster, and easier to reason about.

Enabling FinalizationRegistry in Workers

Given its non-deterministic nature and limited early adoption, we initially disabled the FinalizationRegistry API in our runtime. However, as usage of Wasm-based Workers grew — particularly among high-traffic customers — we began to see new demands emerge. One such customer was running an extremely high requests per second (RPS) workload using WebAssembly, and needed tight control over memory to sustain massive traffic spikes without degradation. This highlighted a gap in our memory management capabilities, especially in cases where manual cleanup wasn’t always feasible or reliable. As a result, we re-evaluated our stance and began exploring the challenges and trade-offs of enabling FinalizationRegistry within the Workers environment, despite its known limitations.

Preventing footguns with safe defaults

Because this API could be misused and cause unpredictable results for our customers, we’ve added a few safeguards. Most importantly, cleanup callbacks are run without an active async context, which means they cannot perform any I/O. This includes sending events to a tail Worker, logging metrics, or making fetch requests.

While this might sound limiting, it’s very intentional. Finalization callbacks are meant for cleanup — especially for releasing WebAssembly memory — not for triggering side effects. If we allowed I/O here, developers might (accidentally) rely on finalizers to perform critical logic that depends on when garbage collection happens. That timing is non-deterministic and outside your control, which could lead to flaky, hard-to-debug behavior.

We don’t have full control over when V8’s garbage collector performs cleanup, but V8 does let us nudge the timing of finalizer execution. Like Node and Deno, Workers queue FinalizationRegistry jobs only after the microtask queue has drained, so each cleanup batch slips into the quiet slots between I/O phases of the event loop.


Security concerns

The Cloudflare Workers runtime is specifically engineered to prevent side-channel attacks in a multi-tenant environment. Prior to enabling the FinalizationRegistry API, we did a thorough analysis to assess its impact on our security model and determine the necessity of additional safeguards. The non-deterministic nature of FinalizationRegistry raised concerns about potential information leaks leading to Spectre-like vulnerabilities, particularly regarding the possibility of exploiting the garbage collector (GC) as a confused deputy or using it to create a timer.

GC as confused deputy

One concern was whether the garbage collector (GC) could act as a confused deputy — a security antipattern where a privileged component is tricked into misusing its authority on behalf of untrusted code. In theory, a clever attacker could try to exploit the GC’s ability to access internal object lifetimes and memory behavior in order to infer or manipulate sensitive information across isolation boundaries.

However, our analysis indicated that the V8 GC is effectively contained and not exposed to confused deputy risks within the runtime. This is attributed to our existing threat models and security measures, such as the isolation of user code, where the V8 Isolate serves as the primary security boundary. Furthermore, even though FinalizationRegistry involves some internal GC mechanics, the callbacks themselves execute in the same isolate that registered them — never across isolates — ensuring isolation remains intact.

GC as timer

We also evaluated the possibility of using FinalizationRegistry as a high-resolution timing mechanism — a common vector in side-channel attacks like Spectre. The concern here is that an attacker could schedule object finalization in a way that indirectly leaks information via the timing of callbacks.

In practice, though, the resolution of such a “GC timer” is low and highly variable, offering poor reliability for side-channel attacks. Additionally, we control when finalizer callbacks are scheduled — delaying them until after the microtask queue has drained — giving us an extra layer of control to limit timing precision and reduce risk.

Following a review with our security research team, we determined that our existing security model is sufficient to support this API.

Predictable cleanups?

JavaScript’s Explicit Resource Management proposal introduces a deterministic approach to handle resources needing manual cleanup, such as file handles, network connections, or database sessions. Drawing inspiration from constructs like C#’s using and Python’s with, this proposal introduces the using and await using syntax. This new syntax guarantees that objects adhering to a specific cleanup protocol are automatically disposed of when they are no longer within their scope.

Let’s look at a simple example to understand it a bit better.

class MyResource {
  [Symbol.dispose]() {
    console.log("Resource cleaned up!");
  }

  use() {
    console.log("Using the resource...");
  }
}

{
  using res = new MyResource();
  res.use();
} // When this block ends, Symbol.dispose is called automatically (and deterministically).

The proposal also includes additional features that offer finer control over when dispose methods are called. But at a high level, it provides a much-needed, deterministic way to manage resource cleanup. Let’s now update our earlier WebAssembly-based example to take advantage of this new mechanism instead of relying on FinalizationRegistry:

const { instance } = await WebAssembly.instantiate(WasmBytes, {});
const { memory, make_buffer, free_buffer } = instance.exports;

class WasmBuffer {
  constructor(ptr, len) {
    this.ptr = ptr;
    this.len = len;
  }

  [Symbol.dispose]() {
    free_buffer(this.ptr, this.len);
  }
}

{
  const lenPtr = 0;
  const ptr = make_buffer(lenPtr);
  const len = new DataView(memory.buffer).getUint32(lenPtr, true);

  using buf = new WasmBuffer(ptr, len);

  const data = new Uint8Array(memory.buffer, ptr, len);
  console.log(new TextDecoder().decode(data));  // → “Hello from Rust”
} // Symbol.dispose or free_buffer gets called deterministically here

Explicit Resource Management provides a more dependable way to clean up resources than FinalizationRegistry, as it runs cleanup logic — such as calling free_buffer in WasmBuffer via [Symbol.dispose]() and the using syntax — deterministically, rather than relying on the garbage collector’s unpredictable timing. This makes it a more reliable choice for managing critical resources, especially memory.

Future

Emscripten already makes use of Explicit Resource Management for handling Wasm memory, using FinalizationRegistry as a last resort, while wasm-bindgen supports it in experimental mode. The proposal has seen growing adoption across the ecosystem and was recently conditionally advanced to Stage 4 in the TC39 process, meaning it’ll soon officially be part of the JavaScript language standard. This reflects a broader shift toward more predictable and structured memory cleanup in WebAssembly applications.

We recently added support for this feature in Cloudflare Workers as well, enabling developers to take advantage of deterministic resource cleanup in edge environments. As support for the feature matures, it’s likely to become a standard practice for managing linear memory safely and reliably.

FinalizationRegistry: still not dead yet?

Explicit Resource Management brings much-needed structure and predictability to resource cleanup in WebAssembly and JavaScript interop applications, but it doesn’t make FinalizationRegistry obsolete. There are still important use cases, particularly when a Wasm-allocated object’s lifecycle is out of your hands or when explicit disposal isn’t practical. In scenarios involving third-party libraries, dynamic lifecycles, or integration layers that don’t follow using patterns, FinalizationRegistry remains a valuable fallback to prevent memory leaks.

Looking ahead, a hybrid approach will likely become the standard in Wasm-JavaScript applications. Developers can use ERM for deterministic cleanup of Wasm memory and other resources, while relying on FinalizationRegistry as a safety net when full control isn’t possible. Together, they offer a more reliable and flexible foundation for managing memory across the JavaScript and WebAssembly boundary.

Ready to try it yourself? Deploy a WebAssembly-powered Worker and experiment with memory management — start building with Cloudflare Workers today.

The collective thoughts of the interwebz